As the end of the 1990s approached, a lot of kernel-development effort was
going into improving support for 32-bit systems
with shockingly large amounts of memory installed. This being the 1990s,
having more than 1GB of memory in such a system was deemed to be shocking.
Many of the compromises made to support such inconceivably large systems
have remained in the kernel to this day. One of those compromises —
bounce buffering of I/O requests in the block layer — has finally been
eased out for the 6.16 release, more than a quarter-century after its
introduction.
Since SUSE is also going to ship Kea DHCP in its products, we
performed a routine review of its code base. Even before checking the
network security of Kea, we stumbled over a range of local security
issues, among them a local root exploit which is possible in many
default installations of Kea on Linux and BSD distributions. […]
This report is based on Kea release 2.6.1. Any source code
references in this report relate to this version. Many systems still
ship older releases of Kea, but we believe they are all affected as
well by the issues described in this report.
The report details seven security issues including local-privilege-escalation
and arbitrary file overwrite
vulnerabilities. Security fixes for the vulnerabilities have been
published in all of the currently supported release series of Kea: 2.4.2, 2.6.3,
and the 2.7.9
development release were all released on May 28. Kea has assigned CVE-2025-32801, CVE-2025-32802,
and CVE-2025-32803 to the vulnerabilities. Note that some of the CVEs
cover multiple security flaws.
This post was coauthored with engineers at Cash App, including Ben Apprederisse (Platform Engineering Technical Lead), Jan Zantinge (Traffic Engineer), and Rachel Sheikh (Compute Engineer).
Cash App, a leading peer-to-peer payments and digital wallet service from Block, Inc., has grown to serve over 57 million users since its launch in 2013. Providing diverse offerings like instant money transfers, debit cards, stock and bitcoin investments, personal loans, and tax filing, Cash App continuously strives to make money more relatable, accessible, and secure. To meet this mission, their platform built on AWS must remain highly scalable and resilient.
Cash App has implemented resilience improvements across the entire technology stack, but for this post, we explore two enhancements implemented in 2024. First, we discuss how Cash App improved the resilience of its compute platform built on Amazon Elastic Kubernetes Service (Amazon EKS) by implementing a dual-cluster topology to reduce single points of failure. We also discuss how Cash App used AWS Fault Injection Service (AWS FIS) to conduct an Availability Zone power interruption scenario in non-production environments, preparing the platform team for real-world failures and ongoing regulatory requirements.
Moving to Amazon EKS
Cash App has used Amazon EKS as a shared platform for years, and in 2024, we migrated the last of our biggest and most critical services to it, driven by the ease of management and our strategy to run workloads in the cloud. This shift empowered our teams to focus more on application delivery and less on cluster management, abstracting away some of the complexity in operating Kubernetes clusters. With Amazon EKS, AWS is responsible for managing the Kubernetes control plane, which includes the control plane nodes, the ETCD database, and other infrastructure necessary for AWS to deliver a service offering with enhanced security features. As a consumer of Amazon EKS, we are still responsible for things like AWS Identity and Access Management (IAM), pod security, runtime security, networking, and cluster automatic scaling in the data plane for worker nodes. AWS refers to this as the Shared Responsibility Model; for more details, refer to Best Practices for Security. For a while, maintaining a single shared EKS cluster for each environment and AWS Region was acceptable and met our technical requirements.
Scaling challenges with a single shared EKS cluster
As Cash App’s shared EKS cluster grew and onboarded hundreds of microservices, we became an early adopter of the Karpenter Cluster Autoscaler, which improved application availability and cluster efficiency. Karpenter was designed to enhance node lifecycle management within Kubernetes clusters. It automates provisioning and deprovisioning of nodes based on the specific scheduling needs of pods, allowing for efficient scaling and cost optimization. We also reviewed and adopted many of the Amazon EKS Best Practices Guides for Reliability, Security, Networking, and Scalability.
Despite these efforts, in 2023, we realized having a single shared EKS cluster with hundreds of worker nodes had become a critical dependency in our cloud platform architecture, whereby standard operations like cluster upgrades posed a risk of impacting production traffic or causing downtime. Although we had a staging environment that allowed us to test new features and changes before rolling them out in production, it didn’t always reflect real traffic patterns that could allow impactful changes to go unnoticed in lower environments. For example, in late 2023, production traffic was briefly impacted due to a relatively new Kubernetes feature called API Priority and Fairness (APF) that introduced temporary control plane throttling following a cluster upgrade.
As a leader in the financial services industry, any interruption to our services directly impacts customers’ ability to transact and participate in the economy, so round-the-clock availability of our platform is essential. Following this incident, we reviewed and implemented the Kubernetes Control Plane best practices pertaining to APF and set up new detections in our observability platform to monitor things like FlowSchemas and queue depth. We also created a business case for investing in platform evolution and moving towards a multi-cluster topology. The desired state was to have a safer way to upgrade clusters, such that traffic is always serviceable regardless of the state of a single cluster in the fleet.
The following diagram illustrates our basic architecture in late 2023, portraying a single, Multi-AZ EKS cluster at Cash App. We had two ingress paths: for public ingress, we used Amazon Route 53 to a Network Load Balancer (NLB). For internal ingress across Amazon Virtual Private Cloud (Amazon VPC) networks (for example, from other business units), we set up a VPC endpoint service. Other components (such as service dependencies like database clusters and other Regions) are intentionally omitted from the diagram for simplicity.
Enterprise network architecture showcasing secure cross-VPC communication via PrivateLink to shared EKS cluster with public/internal ingress
Platform enhancements
In 2024, our cloud platform team implemented architectural changes to improve the reliability of the shared Amazon EKS platform, which was already running hundreds of services and over 10,000 pods. In the process, we also recognized the importance of chaos engineering to provide controlled failure testing and preparedness, which is also an evolving regulatory requirement for financial institutions. Our team has made multiple resilience improvements to apply long-term scalability; the rest of this post focuses on two enhancements we believe other AWS customers can benefit from.
Enhancement 1: Implementing a dual-cluster topology
When researching multi-cluster topologies and interacting with AWS specialists, we learned about architectural patterns to improve platform resilience with varying degrees of complexity. This included cell-based architecture, Route 53 weighted routing, and NLB chaining, among other patterns. Our initial requirements for the multi-cluster architecture were as follows:
Effortlessly deploy a service across two or more clusters
Serve production traffic from multiple clusters at the same time if needed
Seamlessly upgrade a production cluster without impacting production traffic
Have the ability to take a cluster out of the traffic flow during planned and unplanned events
Achieve reliability improvements with minimal architectural and cost changes
Based on these initial requirements and the complexity required to properly implement a cell-based architecture, we decided to start with Route 53 weighted routing for public ingress, and NLB chaining for internal ingress to achieve immediate improvements. Although we plan to implement a cell-based architecture in the future, it requires careful consideration and engineering investment (for example, creating a cell router and cell provisioning system). At the time, we needed a simpler, short-term solution that could improve overall scalability and reliability. From a Kubernetes perspective, we started with two Multi-AZ clusters in our production environment, each operating independently, such that a planned or unplanned event in one cluster would not affect the other cluster. Existing pipelines were extended to deploy the same Kubernetes resources into both clusters, which would actively serve ingress traffic using an NLB. If needed, we could divert all ingress traffic to one cluster during planned or unplanned events by updating the weights in Route 53 (for public ingress) or updating the listener rules and target groups on the frontend NLB (for internal ingress). In the following sections, we dive deeper into both approaches.
Public ingress changes
For public ingress, requests are still handled by Route 53. With the introduction of weighted routing, requests can be evenly routed between the two backend NLBs (one per cluster). This setup allows Cash App to split traffic evenly across clusters or temporarily route all traffic to one cluster during upgrades. As an example, during cluster A’s upgrade, we can direct ingress traffic to cluster B, enabling a sequential upgrade process with minimal disruption. This dual-cluster approach helps mitigate single points of failure and establishes a foundation for reliability improvements. The following diagram illustrates this architecture.
Highly available architecture using Route 53 for 50/50 traffic distribution to dual NLB and EKS clusters across three AZs
Internal ingress changes
Cash App works closely with other business units like Square, and therefore needs to have a secure and scalable ingress path for cross-VPC traffic. To support these use cases, internal ingress requests are still routed from other business unit VPCs to the NLB associated with our VPC endpoint service. From there, requests are load balanced roughly evenly to two backend NLBs (one per cluster) using the listener rules. The following diagram illustrates this architecture.
Cash App architecture featuring secure VPC peering, tiered load balancing, and redundant EKS clusters for high availability
Key considerations
Consider the following when assessing these approaches:
The NLB chaining approach used for internal ingress enables controlled failover and maintenance with minimal disruption by adjusting NLB listeners and target groups, and reduces single points of failure by distributing requests across two or more clusters.
Although this pattern met our initial requirements and made it possible to shift traffic from one cluster to another, it’s not as granular as we would like (for example, shift traffic for only service A to cluster B, and leave all other traffic on cluster A). We will continue to evolve the architecture and implement a more intelligent ingress router and cell provisioning system. Furthermore, at the time of writing, NLB doesn’t support weighted target group routing.
Using the NLB chaining approach adds additional cost due to multiple NLBs in the traffic path. With NLBs, you’re charged for each hour or partial hour that an NLB is running, and the number of Network Load Balancer Capacity Units (NLCUs) used by the NLB per hour.
The NLB chaining approach doesn’t achieve the full benefits of a cell-based architecture, which provides greater isolation and fault isolation boundaries. Moving to a cell-based architecture requires more complexity and coordination, so we decided to start with NLB chaining and Route 53 weighted routing for immediate improvements and minimal re-architecture.
Looking forward, we plan to implement a cell-based architecture that aligns with Block’s compute strategy. This will consist of a cell management layer (to create, update, and delete cells) and a cell routing layer (to route requests to the correct cell), which allows for fine-grained traffic routing.
Enhancement 2: Using AWS FIS for Availability Zone power interruption
After moving to a dual-cluster topology, we researched ways to test ongoing platform resilience. Specifically, we wanted to test what would happen to our environment during single Availability Zone impairments and how our services and data stores would recover. This led us to AWS FIS, which we could use to conduct an Availability Zone power interruption scenario in our staging environment. AWS FIS is a fully managed service for running fault injection experiments on AWS infrastructure, making it straightforward to get started with chaos engineering. Chaos engineering is the practice of stressing an application in testing or production environments by creating disruptive events, such as a sudden increase in CPU or memory consumption, observing how the system responds, and implementing improvements.
Our initial AWS FIS experiment used multiple actions, including network disruption, database failover (targeting Amazon Aurora and Amazon ElastiCache clusters), and EKS worker node disruption (pod eviction and rescheduling). For the full list of AWS FIS actions, refer to AZ Availability: Power Interruption. For our initial experiment, we targeted infrastructure in a single staging account; however, AWS FIS supports multi-account experiments by setting up an orchestrator account that enables centralized configuration, management, and logging. The orchestrator account owns the AWS FIS experiment template. For future AWS FIS experiments, we plan to target more accounts and resources, operating within the constraints of AWS FIS quotas and limits.
For clear communication during the AWS FIS experiment, our platform team coordinated with internal application stakeholders and our AWS account team, monitoring metrics to gauge failover and recovery responses. After the experiment, we debriefed with AWS teams and submitted product feature requests to support ongoing service evolution. Moving forward, we plan to conduct AWS FIS experiments at least twice a year to reinforce reliability best practices and adhere to ongoing regulatory requirements. We will also diversify the types of fault injection experiments we perform, and expand beyond the single Availability Zone failure tests. For example, we might introduce a capability that allows application teams to perform one-time AWS FIS experiments just for their service and backend database infrastructure in a controlled, self-service fashion. An added benefit of using AWS FIS is that there is no agent or infrastructure to deploy or manage, and you’re only billed for the duration of the experiment. This made it both straightforward and affordable to get started with chaos engineering. The following diagram illustrates the architecture of the Availability Zone power interruption scenario targeting subnets, compute, and database clusters.
AWS Fault Injection Service AZ Availability: Power Interruption scenario
Key considerations
Setting up the AWS FIS experiment required us to modify default service limits and quotas to accommodate the scale and scope, such as the number of target resources for ElastiCache, Amazon Relational Database Service (Amazon RDS), and subnets. We recommend reviewing the quotas, service limits, and supported services prior to conducting your own experiment, and collaborate with your AWS account team to achieve a seamless experience.
We also learned that certain failures, such as database failover, require more than network disruption actions alone—specific failover actions had to be configured in the AWS FIS experiment template to trigger the desired behavior, as outlined further in the service documentation. If you’re starting with the Availability Zone power interruption scenario, be sure to include all of the required actions to achieve the desired outcome. Finally, we recommend using AWS FIS in lower environments because AWS FIS actions will have real impact on the targeted resource state and availability.
Conclusion
Through these enhancements, Cash App has improved overall resilience posture and laid the groundwork for future improvements. On the Amazon EKS side, we aim to implement an ingress routing layer through cell-based architecture patterns, enabling more granular traffic routing and improved fault isolation boundaries. We will continue to use Karpenter for cluster automatic scaling, and are in the process of rolling out AWS Graviton based instances to further improve resource efficiency. Finally, we will continue using AWS FIS for chaos engineering at both the platform and application level, performing larger-scale AWS FIS experiments with more complexity.
For other blog posts and related resources, refer to:
This post was cowritten with Steven Aerts and Reza Radmehr from Airties.
Airties is a wireless networking company that provides AI-driven solutions for enhancing home connectivity. Founded in 2004, Airties specializes in developing software and hardware for wireless home networking, including Wi-Fi mesh systems, extenders, and routers. The flagship software as a service (SaaS) product, Airties Home, is an AI-driven platform designed to automate customer experience management for home connectivity, offering proactive customer care, network optimization, and real-time insights. By using AWS managed services, Airties can focus on their core mission: improving home Wi-Fi experiences through automated optimization and proactive issue resolution. This includes minimizing network downtime, enabling faster diagnostic capabilities for troubleshooting, and enhancing overall Wi-Fi quality. The solution has demonstrated significant impact in reducing both the frequency of help desk calls and average call duration, leading to improved customer satisfaction and reduced operational costs for Airties while delivering enhanced service quality to their customers and the end-users.
In 2023, Airties initiated a strategic migration from Apache Kafka running on Amazon Elastic Compute Cloud (Amazon EC2) to Amazon Kinesis Data Streams. Prior to this migration, Airties operated multiple fixed-size Kafka clusters, each deployed in a single Availability Zone to minimize cross-AZ traffic costs. Although this architecture served its purpose, it required constant monitoring and manual scaling to handle varying data loads. The transition to Kinesis Data Streams marked a significant step in their cloud optimization journey, enabling true serverless operations with automatic scaling capabilities. This migration resulted in substantial infrastructure cost reduction while improving system reliability, eliminating the need for manual cluster management and capacity planning.
This post explores the strategies the Airties team employed during this transformation, the challenges they overcame, and how they achieved a more efficient, scalable, and maintenance-free streaming infrastructure.
Kafka use cases for Airties workloads
Airties continuously ingests data from tens of millions of access points (such as modems and routers) using AWS IoT Core. Before the transition, these messages were queued and stored within multiple siloed Kafka clusters, with each cluster deployed in a separate Availability Zone to minimize cross-AZ traffic costs. This fragmented architecture created several operational challenges. The segmented data storage required complex extract, transform, and load (ETL) processes to consolidate information across clusters, increasing the time to derive meaningful insights. The data collected serves multiple critical purposes—from real-time monitoring and reactive troubleshooting to predictive maintenance and historical analysis. However, the siloed nature of the data storage made it particularly challenging to perform cross-cluster analytics and delayed the ability to identify network-wide patterns and trends.
The data processing architecture at Airties served two distinct use cases. The first was a traditional streaming pattern with a batch reader processing data in bulk for analytical purposes. The second use case used Kafka as a queryable data store—a pattern that, though unconventional, has become increasingly common in large-scale data architectures.
For this second use case, Airties needed to provide immediate access to historical device data when troubleshooting customer issues or analyzing specific network events. This was implemented by maintaining a mapping of data points to their Kafka offsets in a database. When customer support or analytics teams needed to retrieve specific historical data, they could quickly locate and fetch the exact records from high-retention Kafka topics using these stored offsets. This approach eliminated the need for a separate database system while maintaining fast access to historical data.
To handle the massive scale of operations, this solution was horizontally scaled across dozens of Kafka clusters, with each cluster responsible for managing approximately 25 TB of records.
The following diagram illustrates the previous Kafka-based architecture.
Challenges with the Kafka-based architecture
At Airties, managing and scaling Kafka clusters has presented several challenges, hindering the organization from focusing on delivering business value effectively:
Operational overhead: Maintaining and monitoring Kafka clusters requires significant manual effort and operational overhead at Airties. Tasks such as managing cluster upgrades, handling hardware failures and rotation, and conducting load testing constantly demand engineering attention. These operational tasks take away from the team’s ability to concentrate on core business functions and value-adding activities within the company.
Scaling complexities : The process of scaling Kafka clusters involves multiple manual steps that create operational burden for the cloud team. These include configuring new brokers, rebalancing partitions across nodes, and providing proper data distribution—all while maintaining system stability. As data volume and throughput requirements fluctuate, scaling typically involves adding or removing entire Kafka clusters, which is a complex and time-consuming process for the Airties team.
Right-sizing cluster capacity: The static nature of Kafka clusters created a “one-size-fits-none” situation for Airties. For large-scale deployments with high data volumes and throughput requirements, adding new clusters required significant manual work, including capacity planning, broker configuration, and partition rebalancing, making it inefficient for handling dynamic scaling needs. Conversely, for smaller deployments, the standard cluster size was oversized, leading to resource waste and unnecessary costs.
How the new architecture addresses these challenges
The Airties team needed to find a scalable, high-performance, and cost-effective solution for real-time data processing that would allow seamless scaling with increasing data volumes. Data durability was a critical requirement, because losing device telemetry data would create permanent gaps in customer analytics and historical troubleshooting capabilities. Although temporary delays in data access could be tolerated, the loss of any device data point was unacceptable for maintaining service quality and customer support effectiveness.
To address these challenges, Airties implemented two different approaches for different scenarios.
The primary use case was real-time data streaming with Kinesis Data Streams. Airties replaced Kafka with Kinesis Data Streams to handle the continuous ingestion and processing of telemetry data from tens of millions of endpoints. This shift offered significant advantages:
Auto-scaling capabilities : Kinesis Data Streams can be scaled through simple API calls, alleviating the need for complex configurations and manual interventions.
Stream isolation : Each stream operates independently, meaning scaling operations on one stream have no impact on others. This alleviated the risks associated with cluster-wide changes in their previous Kafka setup.
Dynamic shard management : Unlike Kafka, where changing the number of partitions requires creating a new topic, Kinesis Data Streams allows adding or removing shards dynamically without losing message ordering within a partition.
Application Auto Scaling: Airties implemented AWS Application Auto Scaling with Kinesis Data Streams, allowing the system to automatically adjust the number of shards based on actual usage patterns and throughput requirements.
These features empowered Airties to efficiently manage resources, optimizing costs during periods of lower activity while seamlessly scaling up to handle peak loads.
For providing on-demand access to historical device data, Airties implemented a decoupled architecture that separates streaming, storage, and data access concerns. This approach replaced the previous solution where historical data was stored directly in Kafka topics. The new architecture consists of several key components working together:
Data collection and processing : The architecture begins with a consumer application that processes data from Kinesis Data Streams. This application implements analyzing the data, as making it available for detailed historical analysis. The result of the data analysis is written to Amazon Data Firehose, which buffers the data, writing it regularly to Amazon Simple Storage Service (Amazon S3), where it can later be picked up by Amazon EMR. This path is optimized for efficient storage and bulk reading from Amazon S3 by Amazon EMR. For raw data storage, multiple raw data samples are batched together in bulk files, which are stored in a separate Amazon S3 path. This path is optimized for storage efficiency and fetching raw data using Amazon S3 range queries.
Indexing and metadata management: To enable fast data retrieval, the architecture implements a sophisticated indexing system. For each record in the uploaded bulk files, two crucial pieces of information are recorded in an Amazon DynamoDB table: the Amazon S3 location (bucket and key) where the bulk file was written, and the sequence number of the corresponding data record in the Kinesis Data Streams queue. This indexing strategy provides low-latency access to specific data points, efficient querying capabilities for both real-time and historical data, automatic scaling to handle increasing data volumes, and high availability for metadata lookups.
Ad-hoc data retrieval: When specific historical data needs to be accessed, the system follows an efficient retrieval process. First, the application queries the DynamoDB table using the relevant identifiers. The query returns the exact Amazon S3 location and offset where the required data is stored. The application then fetches the specific data directly from Amazon S3 using range queries. This approach enables quick access to historical data points, minimal data transfer costs by retrieving only needed records, efficient troubleshooting and analysis workflows, and reduced latency for customer support operations.
This decoupled architecture uses the strengths of each AWS service: Amazon Kinesis Data Streams provides scalable and reliable real-time data streaming, while Amazon S3 delivers durable and cost-effective object storage for raw data, and Amazon DynamoDB enables fast and flexible storage of metadata and indexing. By separating streaming from storage and utilizing each service for its specific strengths, Airties created a more cost-effective and scalable solution for ad-hoc data access needs, aligning each component with its optimal AWS service. The new architecture not only improved data access performance but also significantly reduced operational complexity. Instead of managing Kafka topics for historical data storage, Airties now benefits from fully managed AWS services that automatically handle scaling, durability, and availability. This approach has proven particularly valuable for customer support scenarios, where quick access to historical device data is crucial for resolving issues efficiently.
Solution overview
Airties’s new architecture involves several critical components, including efficient data ingestion, indexing with AWS Lambda functions, optimized data aggregation and processing, and comprehensive monitoring and management practices using Amazon CloudWatch. The following diagram illustrates this architecture.
The new architecture consists of the following key stages:
Data collection and storage: The data journey begins with Kinesis Data Streams, which ingests real-time data from millions of access points. This streaming data is then processed by a consumer application that batches the data into bulk files (also known as briefcase files) for efficient storage in Amazon S3. This approach of streaming, batching, and then storing minimizes write operations and reduces overall costs, while providing data durability through built-in replication in Amazon S3. When the data is in Amazon S3, it’s readily available for both immediate processing and long-term analysis. The processing pipeline continues with aggregators that read data from Amazon S3, process it, and store aggregated results back in Amazon S3. By integrating AWS Glue for ETL operations and Amazon Athena for SQL-based querying, Airties can process large volumes of data efficiently and generate insights quickly and cost-effectively.
Data aggregation and bulk file creation: The aggregators play a crucial role in the initial data processing. They aggregate the incoming data based on predefined criteria and create bulk files. This aggregation process reduces the volume of data that needs to be processed in subsequent steps, optimizing the overall data processing workflow. The aggregators then write these bulk files directly to Amazon S3.
Indexing: Upon successful upload of a bulk file to Amazon S3 by the aggregators, the aggregator will write an index entry for the bulk file an Amazon DynamoDB table. This indexing mechanism allows for efficient retrieval of data based on device IDs and timestamps, facilitating quick access to relevant data using S3 range queries on the bulk files.
Further processing and analysis: The bulk files stored in Amazon S3 are now in a format optimized for querying and analysis. These files can be further processed using AWS Glue and analyzed using Athena, allowing for complex queries and in-depth data exploration without the need for additional data transformation steps.
Monitoring and management: To maintain the reliability and performance of the Kafka-less architecture, comprehensive monitoring and management practices were implemented. CloudWatch provides real-time monitoring of system performance and resource utilization, allowing for proactive management of potential issues. Additionally, automated alerts and notifications make sure anomalies are promptly addressed.
Results and benefits
The transition to this new architecture yielded significant benefits for Airties:
Scalability and performance: The new architecture empowers Airties to scale seamlessly with increasing data volumes. The ability to independently scale reader and writer operations has reduced performance impacts during high-demand periods. This is a significant improvement over the previous Kafka-based system, where scaling often required complex reconfigurations and could affect the entire cluster. With Kinesis Data Streams, Airties can now handle peak loads effortlessly while optimizing resource usage during quieter periods.
Reliability and fault tolerance: By using AWS managed services, Airties has significantly reduced system latency and improved overall uptime. The automatic data replication and recovery processes of Kinesis Data Streams provide enhanced data durability, a critical requirement for Airties’s operations. The improved high availability means that Airties can now offer more reliable services to their customers, minimizing disruptions and enhancing the overall quality of their home connectivity solutions.
Operational efficiency: The new architecture has dramatically reduced the need for manual intervention in capacity management. This shift has freed up valuable engineering resources, allowing the team to focus on delivering business value rather than managing infrastructure. The simplified operational model has increased the team’s productivity, empowering them to innovate faster and respond more quickly to customer needs. The reduction in operational overhead has also led to faster deployment cycles and more frequent feature releases, enhancing Airties’s competitiveness in the market.
Environmental impact and sustainability: The transition to a serverless architecture demonstrated significant environmental benefits, achieving a remarkable 40% reduction in energy consumption. This substantial decrease in energy usage was achieved by eliminating the need for constantly running EC2 instances and using more efficient, managed AWS services. This improvement in energy efficiency aligns with Airties’s commitment to environmental sustainability and establishes them as an environmentally responsible leader in the tech industry.
Cost optimization: The financial benefits of transitioning to a Kafka-less architecture are clearly demonstrated through comprehensive AWS Cost Explorer data. As shown in the following diagram, the total cost breakdown across all relevant services from January to July includes EC2 instances, DynamoDB, other Amazon EC2 costs, Kinesis Data Streams, Amazon S3, and Amazon Data Firehose. The most notable change was a 33% reduction in total monthly infrastructure costs (compared to January baseline), primarily achieved through significant decrease in Amazon EC2 related costs as the migration progressed, elimination of dedicated Kafka infrastructure, and efficient use of the AWS pay-as-you-go model. Although new costs were introduced for managed services (DynamoDB, Kinesis Data Streams, Amazon Data Firehose, Amazon S3), the overall monthly AWS costs maintained a clear downward trend. With these cost savings, Airties can offer more competitive pricing to their customers. The diagram below shows monthly cost breakdown during the transition.
Conclusion
The transition to this new architecture with Kinesis Data Streams has marked a significant milestone in Airties’s journey towards operational excellence and sustainability. These initiatives have not only enhanced system performance and scalability, but have also resulted in substantial cost savings (33%) and energy efficiency (40%). By using advanced technologies and innovative solutions on AWS, the Airties team continues to set the benchmark for efficient, reliable, and sustainable operations, while paving the way for a sustainable future. In order to explore how you can modernize your streaming architecture with AWS, see the Kinesis Data Streams documentation and watch this re:invent session on serverless data streaming with Kinesis Data Streams and AWS Lambda.
About the Authors
Steven Aerts is a principal software engineer at Airties, where his team is responsible for ingesting, processing, and analyzing the data of tens of millions of homes to improve their Wi-Fi experience. He was a speaker at conferences like Devoxx and AWS Summit Dubai, and is an open source contributor.
Reza Radmehr is a Sr. Leader of Cloud Infrastructure and Operations at Airties, where he leads AWS infrastructure design, DevOps and SRE automation, and FinOps practices. He focuses on building scalable, cost-efficient, and reliable systems, driving operational excellence through smart, data-driven cloud strategies. He is passionate about blending financial insight with technical innovation to improve performance and efficiency at scale.
Ramazan Ginkaya is a Sr. Technical Account Manager at AWS with over 17 years of experience in IT, telecommunications, and cloud computing. He is a passionate problem-solver, providing technical guidance to AWS customers to help them achieve operational excellence and maximize the value of cloud computing.
Cloudflare Workers Builds is our CI/CD product that makes it easy to build and deploy Workers applications every time code is pushed to GitHub or GitLab. What makes Workers Builds special is that projects can be built and deployed with minimal configuration.Just hook up your project and let us take care of the rest!
But what happens when things go wrong, such as failing to install tools or dependencies? What usually happens is that we don’t fix the problem until a customer contacts us about it, at which point many other customers have likely faced the same issue. This can be a frustrating experience for both us and our customers because of the lag time between issues occurring and us fixing them.
We want Workers Builds to be reliable, fast, and easy to use so that developers can focus on building, not dealing with our bugs. That’s why we recently started building an error detection system that can detect, categorize, and surface all build issues occurring on Workers Builds, enabling us to proactively fix issues and add missing features.
In this post, we will dive into how we used the Cloudflare Developer Platform to check for issues across more than 1 million Durable Objects.
Background: Workers Builds architecture
Back in October 2024, we wrote abouthow we built Workers Builds entirely on the Workers platform. To recap, Builds is built using Workers, Durable Objects, Workers KV, R2, Queues, Hyperdrive, and a Postgres database. Some of these things were not present when launched back in October (for example, Queues and KV). But the core of the architecture is the same.
A client Worker receives GitHub/GitLab webhooks and stores build metadata in Postgres (via Hyperdrive). A build management Worker uses two Durable Object classes: a Scheduler class to find builds in Postgres that need scheduling, and a class called BuildBuddy to manage the lifecycle of a build. When a build needs to be started, Scheduler creates a new BuildBuddy instance which is responsible for creating a container for the build (usingCloudflare Containers), monitoring the container with health checks, and receiving build logs so that they can be viewed in the Cloudflare Dashboard.
In addition to this core scheduling logic, we have several Workers Queues for background work such as sending PR comments to GitHub/GitLab.
The problem: builds are failing
While this architecture has worked well for us so far, we found ourselves with a problem: compared toCloudflare Pages, a concerning percentage of builds were failing. We needed to dig deeper and figure out what was wrong, and understand how we could improve Workers Builds so that developers can focus more on shipping instead of build failures.
Types of build failures
Not all build failures are the same. We have several categories of failures that we monitor:
Initialization failures: when the container fails to start.
Clone failures: failing to clone the repository from GitHub/GitLab.
Build timeouts: builds that ran past the limit and were terminated by BuildBuddy.
Builds failing health checks: the container stopped responding to health checks, e.g. the container crashed for an unknown reason.
Failure to install tools or dependencies.
Failed user build/deploy commands.
The first few failure types were straightforward, and we’ve been able to track down and fix issues in our build system and control plane to improve what we call “build completion rate”. We define build completion as the following:
We successfully started the build.
We attempted to install tools/dependencies (considering failures as “user error”).
We attempted to run the user-defined build/deploy commands (again, considering failures as “user error”).
We successfully marked the build as stopped in our database.
For example, we had a bug where builds for a deleted Worker would attempt to run and continuously fail, which affected our build completion rate metric.
User error
We’ve made a lot of progress improving the reliability of build and container orchestration, but we had a significant percentage of build failures in the “user error” metric. We started asking ourselves “is this actually user error? Or is there a problem with the product itself?”
This presented a challenge because questions like “did the build command fail due to a bug in the build system, or user error?” are a lot harder to answer than pass/fail issues like failing to create a container for the build. To answer these questions, we had to build something new, something smarter.
Build logs
The most obvious way to determine why a build failed is to look at its logs. When spot-checking build failures, we can typically identify what went wrong. For example, some builds fail to install dependencies because of an out of date lockfile (e.g. package-lock.json out of date with package.json). But looking through build failures one by one doesn’t scale. We didn’t want engineers looking through customer build logs without at least suspecting that there was an issue with our build system that we could fix.
Automating error detection
At this point, next steps were clear: we needed an automated way to identify why a build failed based on build logs, and provide a way for engineers to see what the top issues were while ensuring privacy (e.g. removing account-specific identifiers and file paths from the aggregate data).
Detecting errors in build logs using Workers Queues
The first thing we needed was a way to categorize build errors after a build fails. To do this, we created a queue named BuildErrorsQueue to process builds and look for errors. After a build fails, BuildBuddy will send the build ID to BuildErrorsQueue which fetches the logs, checks for issues, and saves results to Postgres.
We started out with a few static patterns to match things like Wrangler errors in log lines:
It wouldn’t be useful if all Wrangler errors were grouped under a single generic “wrangler_error” code, so we further grouped them by normalizing the log lines into groups:
function getWranglerLogGroupFromLogLine(
  logLine: LogLine,
  regexMatchers: RegexMatcher[]
): string {
  const original = logLine[2].trim().replaceAll(/[\t\n\r]+/g, ' ')
  let message = original
  let group = original
  for (const { mustMatch, patterns, stopOnMatch, name, useNameAsGroup } of regexMatchers) {
    if (mustMatch !== undefined) {
      const matched = matchLineToRegexes(message, mustMatch)
      if (!matched) continue
    }
    if (patterns) {
      for (const [pattern, mask] of patterns) {
        message = message.replaceAll(pattern, mask)
      }
    }
    if (useNameAsGroup === true) {
      group = name
    } else {
      group = message
    }
    if (Boolean(stopOnMatch) && message !== original) break
  }
  return group
}

const wranglerRegexMatchers: RegexMatcher[] = [
  {
    name: 'could_not_resolve',
    // ✘ [ERROR] Could not resolve "./balance"
    // ✘ [ERROR] Could not resolve "node:string_decoder" (originally "string_decoder/")
    mustMatch: [/^✘ \[ERROR\] Could not resolve "[@\w :/\\.-]*"/i],
    stopOnMatch: true,
    patterns: [
      [/(?<=^✘ \[ERROR\] Could not resolve ")[@\w :/\\.-]*(?=")/gi, '<MODULE>'],
      [/(?<=\(originally ")[@\w :/\\.-]*(?=")/gi, '<MODULE>'],
    ],
  },
  {
    name: 'no_matching_export_for_import',
    // ✘ [ERROR] No matching export in "src/db/schemas/index.ts" for import "someCoolTable"
    mustMatch: [/^✘ \[ERROR\] No matching export in "/i],
    stopOnMatch: true,
    patterns: [
      [/(?<=^✘ \[ERROR\] No matching export in ")[@~\w:/\\.-]*(?=")/gi, '<MODULE>'],
      [/(?<=" for import ")[\w-]*(?=")/gi, '<IMPORT>'],
    ],
  },
  // ...many more added over time
]
Once we had our error detection matchers and normalizing logic in place, implementing the BuildErrorsQueue consumer was easy:
Here, we’re fetching logs from each build’s BuildBuddy Durable Object, detecting why it failed using the matchers we wrote, and saving errors to the Postgres DB. We also delete any existing errors for when we improve our error detection patterns to prevent subsequent runs from adding duplicate data to our database.
What about historical builds?
The BuildErrorsQueue was great for new builds, but this meant we still didn’t know why all the previous build failures happened other than “user error”. We considered only tracking errors in new builds, but this was unacceptable because it would significantly slow down our ability to improve our error detection system because each iteration would require us to wait days to identify issues we need to prioritize.
Problem: logs are stored across one million+ Durable Objects
Remember how every build has an associated BuildBuddy DO to store logs? This is a great design for ensuring our logging pipeline scales with our customers, but it presented a challenge when trying to aggregate issues based on logs because something would need to go through all historical builds (>1 million at the time) to fetch logs and detect why they failed.
If we were using Go and Kubernetes, we might solve this using a long-running container that goes through all builds and runs our error detection. But how do we solve this in Workers?
How do we backfill errors for historical builds?
At this point, we already had the Queue to process new builds. If we could somehow send all of the old build IDs to the queue, it could scan them all quickly usingQueues concurrent consumers to quickly work through all builds. We thought about hacking together a local script to fetch all of the log IDs and sending them to an API to put them on a queue. But we wanted something more secure and easier to use so that running a new backfill was as simple as an API call.
That’s when an idea hit us: what if we used a Durable Object with alarms to fetch a range of builds and send them to BuildErrorsQueue? At first, it seemed far-fetched, given that Durable Object alarms have a limited amount of work they can do per invocation. But wait, ifAI Agents built on Durable Objects can manage background tasks, why can’t we fetch millions of build IDs and forward them to queues?
Building a Build Errors Agent with Durable Objects
The idea was simple: create a Durable Object class named BuildErrorsAgent and run a single instance that loops through the specified range of builds in the database and sends them to BuildErrorsQueue.
The first thing we did was set up an RPC method to start a backfill and save the parameters inDurable Object KV storage so that it can be read each time the alarm executes:
async start({
  min_build_id,
  max_build_id,
}: {
  min_build_id: BuildRecord['build_id']
  max_build_id: BuildRecord['build_id']
}): Promise<void> {
  logger.setTags({ handler: 'start', environment: this.env.ENVIRONMENT })
  try {
    if (min_build_id < 0) throw new Error('min_build_id cannot be negative')
    if (max_build_id < min_build_id) {
      throw new Error('max_build_id cannot be less than min_build_id')
    }
    const [started_on, stopped_on] = await Promise.all([
      this.kv.get('started_on'),
      this.kv.get('stopped_on'),
    ])
    await match({ started_on, stopped_on })
      .with({ started_on: P.not(null), stopped_on: P.nullish }, () => {
        throw new Error('BuildErrorsAgent is already running')
      })
      .otherwise(async () => {
        // delete all existing data and start queueing failed builds
        await this.state.storage.deleteAlarm()
        await this.state.storage.deleteAll()
        this.kv.put('started_on', new Date())
        this.kv.put('config', { min_build_id, max_build_id })
        void this.state.storage.setAlarm(this.getNextAlarmDate())
      })
  } catch (e) {
    this.sentry.captureException(e)
    throw e
  }
}
The most important part of the implementation is the alarm that runs every second until the job is complete. Each alarm invocation has the following steps:
Set a new alarm (always first to ensure an error doesn’t cause it to stop).
Retrieve state from KV.
Validate that the agent is supposed to be running:
Ensure the agent is supposed to be running.
Ensure we haven’t reached the max build ID set in the config.
Finally, queue up another batch of builds by querying Postgres and sending to the BuildErrorsQueue.
async alarm(): Promise<void> {
  logger.setTags({ handler: 'alarm', environment: this.env.ENVIRONMENT })
  try {
    void this.state.storage.setAlarm(Date.now() + 1000)
    const kvState = await this.getKVState()
    this.sentry.setContext('BuildErrorsAgent', kvState)
    const ctxLogger = logger.withFields({ state: JSON.stringify(kvState) })

    await match(kvState)
      .with({ started_on: P.nullish }, async () => {
        ctxLogger.info('BuildErrorsAgent is not started, cancelling alarm')
        await this.state.storage.deleteAlarm()
      })
      .with({ stopped_on: P.not(null) }, async () => {
        ctxLogger.info('BuildErrorsAgent is stopped, cancelling alarm')
        await this.state.storage.deleteAlarm()
      })
      .with(
        // we should never have started_on set without config set, but just in case
        { started_on: P.not(null), config: P.nullish },
        async () => {
          const msg =
            'BuildErrorsAgent started but config is empty, stopping and cancelling alarm'
          ctxLogger.error(msg)
          this.sentry.captureException(new Error(msg))
          this.kv.put('stopped_on', new Date())
          await this.state.storage.deleteAlarm()
        }
      )
      .when(
        // make sure there are still builds to enqueue
        (s) =>
          s.latest_build_id !== null &&
          s.config !== null &&
          s.latest_build_id >= s.config.max_build_id,
        async () => {
          ctxLogger.info('BuildErrorsAgent job complete, cancelling alarm')
          this.kv.put('stopped_on', new Date())
          await this.state.storage.deleteAlarm()
        }
      )
      .with(
        {
          started_on: P.not(null),
          stopped_on: P.nullish,
          config: P.not(null),
          latest_build_id: P.any,
        },
        async ({ config, latest_build_id }) => {
          // 1. select batch of ~1000 builds
          // 2. send them to Queues 100 at a time, updating
          //    latest_build_id after each batch is sent
          const failedBuilds = await this.store.builds.selectFailedBuilds({
            min_build_id: latest_build_id !== null ? latest_build_id + 1 : config.min_build_id,
            max_build_id: config.max_build_id,
            limit: 1000,
          })
          if (failedBuilds.length === 0) {
            ctxLogger.info(`BuildErrorsAgent: ran out of builds, stopping and cancelling alarm`)
            this.kv.put('stopped_on', new Date())
            await this.state.storage.deleteAlarm()
          }

          for (
            let i = 0;
            i < BUILDS_PER_ALARM_RUN && i < failedBuilds.length;
            i += QUEUES_BATCH_SIZE
          ) {
            const batch = failedBuilds
              .slice(i, QUEUES_BATCH_SIZE)
              .map((build) => ({ body: build }))

            if (batch.length === 0) {
              ctxLogger.info(`BuildErrorsAgent: ran out of builds in current batch`)
              break
            }
            ctxLogger.info(
              `BuildErrorsAgent: sending ${batch.length} builds to build errors queue`
            )
            await this.env.BUILD_ERRORS_QUEUE.sendBatch(batch)
            this.kv.put(
              'latest_build_id',
              Math.max(...batch.map((m) => m.body.build_id).concat(latest_build_id ?? 0))
            )

            this.kv.put(
              'total_builds_processed',
              ((await this.kv.get('total_builds_processed')) ?? 0) + batch.length
            )
          }
        }
      )
      .otherwise(() => {
        const msg = 'BuildErrorsAgent has nothing to do - this should never happen'
        this.sentry.captureException(msg)
        ctxLogger.info(msg)
      })
  } catch (e) {
    this.sentry.captureException(e)
    throw e
  }
}
Using pattern matching with ts-pattern made it much easier to understand what states we were expecting and what will happen compared to procedural code. We considered using a more powerful library like XState, but decided on ts-pattern due to its simplicity.
Running the backfill
Once everything rolled out, we were able to trigger an errors backfill for over a million failed builds in a couple of hours with a single API call, categorizing 80% of failed builds on the first run. With a fast backfill process, we were able to iterate on our regex matchers to further refine our error detection and improve error grouping. Here’s what the error list looks like in our staging environment:
Fixes and improvements
Having a better understanding of what’s going wrong has already enabled us to make several improvements:
Fixed multiple edge-cases where the wrong package manager was used in TypeScript/JavaScript projects.
Added support for bun.lock (previously only checked for bun.lockb).
Fixed several edge cases where build caching did not work in monorepos.
Projects that use a runtime.txt file to specify a Python version no longer fail.
….and more!
We’re still working on fixing other bugs we’ve found, but we’re making steady progress. Reliability is a feature we’re striving for in Workers Builds, and this project has helped us make meaningful progress towards that goal. Instead of waiting for people to contact support for issues, we’re able to proactively identify and fix issues (and catch regressions more easily).
One of the great things about building on the Developer Platform is how easy it is to ship things. The core of this error detection pipeline (the Queue and Durable Object) only took two days to build, which meant we could spend more time working on improving Workers Builds instead of spending weeks on the error detection pipeline itself.
What’s next?
In addition to continuing to improve build reliability and speed, we’ve also started thinking about other ways to help developers build their applications on Workers. For example, we built aBuilds MCP server that allows users to debug builds directly in Cursor/Claude/etc. We’re also thinking about ways we can expose these detected issues in the Cloudflare Dashboard so that users can identify issues more easily without scrolling through hundreds of logs.
Ready to get started?
Building applications on Workers has never been easier! Try deploying a Durable Object-backed chat application with Workers Builds:
In the course of a penetration testing engagement, Rapid7 discovered three vulnerabilities in MICI Network Co., Ltd’s NetFax server versions < 3.0.1.0. These issues allowed for an authenticated attack chain resulting in Remote Code Execution (RCE) against the device as the root user. While authentication is necessary for exploitation, default credentials for the application are automatically configured to be provided in cleartext through responses sent to the client, allowing for automated exploitation against vulnerable hosts.
Rapid7 enlisted the help of TWCERT to contact the vendor as an intermediary. On Friday, May 2, 2025, Rapid7 received a notification from TWCERT stating the following: “…they (MICI) have responded that they will not address the vulnerability in this product.”
The first vulnerability, a default credential disclosure, started with HTTP GET requests made during initial access to the server which displayed the default System Administrator credentials in cleartext. The display of these credentials appeared to be present due to implemented functionality for support of the ‘OneIn’ client.
Using the credentials, Rapid7 conducted a review of system configuration settings. A lack of sufficient sanitization was found within multiple parameters in regard to the ‘`’ character. This lack of sanitization could be used to store a system command such as ‘whoami’ within the configuration file.
Rapid7 discovered a function that conducted various system tests to confirm valid configuration such as ‘ping’ commands. This function ingested the data from the stored configuration which led to confirmed Remote Code Execution. By using the ‘mkfifo’ and ‘nc’ binaries present within the system, a reverse shell was obtained as the root user.
In addition, within the system it was noted that while the SMTP password displayed within the user interface had been properly redacted, the request which provided the system configuration contained the password in cleartext.
Product Description
MICI’s Network Fax (NetFax) server is a product suite to facilitate receipt of fax messages to user mailboxes through email traffic. The vendor, MICI, operates from Taiwan. During analysis of internet connected devices, Rapid7 noted 34 systems exposed to the internet. Rapid7 notes that the number of devices on internal networks would likely be much higher.
During review, Rapid7 noted systems running on the same ‘wfaxd’ server architecture used in the application with the name ‘CoFax Server’. A majority of those systems were found to be present within Iran. These devices did not necessarily appear to possess the same vulnerabilities from a passive review.
CWE-201: Insertion of Sensitive Information Into Sent Data
Upon accessing the web application on port 80 and intermittently afterwards, a GET request is made to ‘/client.php’ which disclosed default administrative user credentials to clients by providing information contained within an automatically configured setup file:
Remediation:Do not expose user credentials to the client, instead process any occurrences of configuration calls server-side. Present only the necessary information to the client such as the application name and version. Require users to reset the default administrator password upon initial access.
CVE-2025-48046 – Disclosure of Stored Passwords – Moderate (5.3)
Using the credentials, the application was reviewed for security. During this process, the SMTP password configured within the application was found to be properly redacted:
The configuration file, accessed through a GET request to ‘/config.php’ however, provided the cleartext password to the user:
Remediation: Do not expose user credentials to the client. Redact sensitive information before displaying it to the client.
CWE-78: Improper Neutralization of Special Elements used in an OS Command (‘OS Command Injection’)
A server test function which executed commands such as ‘ping’ was located at the /test.php endpoint. This function appeared to ingest data sent to the configuration file such as ‘ETHNAMESERVER’:
The configuration file was changed to include various commands such as a reverse shell using the ‘nc’ binary and ‘whoami’:
The system test was then run, confirming the ‘`’ characters had not been sanitized. This led to remote code execution via command injection. A reverse shell was also obtained through these methods after the existence of the ‘mkfifo’ and ‘nc’ binaries were confirmed to be present on the machine:
Remediation: Properly sanitize all input before use in system commands. While many characters were properly redacted, the ‘`’ character was not. Do server-side validation of configuration settings to confirm all parameters contain expected content before accepting the changes. Fields containing IP addresses should be processed to ensure they contain only valid IP addresses.
A working Metasploit module for this attack path for both a fully unauthenticated Remote Code Execution exploit against servers using default credentials and an authenticated RCE exploitation has been created and will be released in upcoming updates. This attack can be performed by any malicious actor with network access to the device.
Impact
The vulnerabilities have a range of impacts depending on configuration. Disclosure of default credentials by the application poses a risk to system administrators who do not properly change administrative passwords during setup. Rapid7 determined the application did not appear to either enforce or request a changing of default credentials upon initial login.
Failure to obscure passwords to connect to external services could result in compromise of network service accounts and potential impacts to further resources in the environment.
The command injection vulnerabilities result in administrative access to the underlying system, impacting the confidentiality, availability, and integrity of the server and application both.
Vendor Statement
After multiple attempts to contact the vendor without response, Rapid7 elicited the assistance of TWCERT to facilitate communications with the vendor. After multiple correspondences, the vendor indicated the following, as per TWCERT:
“…they (MICI) have responded that they will not address the vulnerability in this product. They advised users not to expose the product to external networks. They stated that they will no longer respond to inquiries regarding this product.”
Remediation
Vendor has indicated that the vulnerabilities will not be patched and advised users that servers should not be exposed to the internet. However, as the vulnerabilities could also be exploited from an internal network perspective and result in administrative access to the underlying server, Rapid7 additionally recommends only exposing the server to strictly necessary internal networks after reviewing the risk of the device’s presence to the environment. Rapid7 recommends changing default device credentials and reviewing risks related to account credentials provided to the system for service integration purposes.
Rapid7 Customers
InsightVM and Nexpose customers should be able to assess their exposure to CVE-2025-48045, CVE-2025-48046 and CVE-2025-48047 with unauthenticated checks available in the May 28, 2025 content release.
Disclosure Timeline
Jan, 2025: Issue discovered by Anna Quinn
Thursday, Jan 30, 2025: Initial disclosure to vendor via contact form
Tuesday, Feb 25, 2025: Additional outreach to vendor via contact form
Tuesday, March 18, 2025: Rapid7 contacts TWCERT to determine proper channels for vendor engagement
Thursday, March 20, 2025: TWCERT puts Rapid7 in touch with vendor
Monday, March 24, 2025: Rapid7 follows up with vendor
Wednesday, March 26, 2025: Rapid7 follows up with vendor
Monday, March 31, 2025: Rapid7 requests additional assistance from TWCERT.
Tuesday, April 1, 2025: TWCERT requests further information
Wednesday, April 2, 2025: TWCERT confirmed receipt of vulnerability disclosure information by vendor and indicated vendor contact would occur after internal review.
Tuesday, April 8, 2025: Rapid7 follows up with vendor and TWCERT, requests an update by April 15, 2025.
Tuesday, April 22, 2025: Rapid7 requests an update
Friday, April 25, 2025: TWCERT relayed message from vendor requesting testing be done on newer versions of application. Rapid7 requests additional version(s) of the affected product from vendor.
Tuesday, April 29, 2025: TWCERT provides a version of NetFax Client for testing, however the vulnerabilities exist in NetFax Server, and as such the client could not be used for validation purposes. Rapid7 informs TWCERT, requests server application versions from vendor.
Friday, May 2, 2025: TWCERT provides a message from vendor indicating the vendor will not address vulnerabilities. Vendor indicates customers should ensure devices are not exposed externally. Vendor states they will not respond to further inquiries on the matter.
The only links are from The Daily Mail and The Mirror, but a marital affair was discovered because the cheater was recorded using his smart toothbrush at home when he was supposed to be at work.
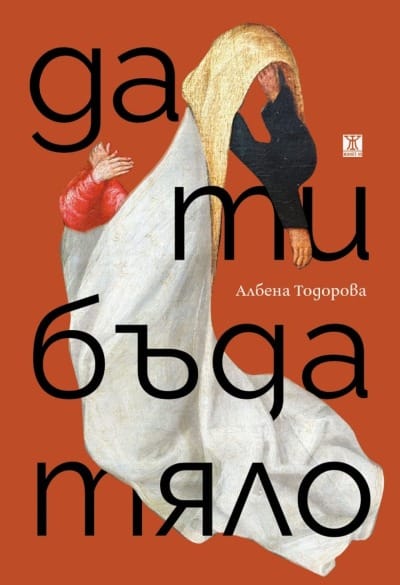
Насред грохота на предчувствията, насред мръсната диря от боклукчийския камион на страха, под затискащия аромат на овошките, който се промъква в линейката, тези стихотворения отварят пространство, в което читателят може да си позволи да бъде внимателен към себе си. Да посрещне чувството, което няма име, и вместо да го пропъди или преименува, да го подслони в детинската „къща“ от играта на гоненица, две ръце над главата, къща от тяло. Домът, който можем да бъдем.
Домът, който един ден ще бъде разрушен, но ненапълно. Защото тайнството на отношенията между тялото и душата още не е разгадано и не знаем кой от тях първи ще каже, че „е тръгнал“ снегът. Защото дори когато тялото е голо и готово в линейката, ароматът на овошките – или на „краката на великан“ – се промъква при него. И дори след смъртта пак потътряме крака обратно към живота.
Тези „внимателни към вниманието“ стихотворения се вглеждат в него и тихо демонтират безсмислените правила, за които нямаме време. Като забраната да наречеш насилника насилник, дори да живее (вече само) вдън сърцето ти. Като неловкостта да запишеш свои препоръки за живеене, по даоистки кратки и мъдри, докато пишеш в женски род. Да използваш своето име в множествено число, като че ли говориш за странно, малко познато животно, „Албените са неми“. Да изкушиш читателя да подпъхне своето име в този стих, своите страхове в твоите, да им бъдеш тяло. Помня времена, когато беше неудобно да говориш за етика в естетическото, сякаш територията на собствено поетическото трябваше да бъде отбранявана на всяка цена.
В тази стихосбирка се вижда как душата на поетическия език може да му бъде тяло.
Преди време приятел предложи като тест за искреност в четенето на поезия кое стихотворение помниш няколко месеца по-късно. Аз бих предложила „на кое стихотворение отваряш, когато самолетът ти минава през гръмотевична буря“ (стр. 52). И „на кое стихотворение се спираш по-дълго на опашката в ИСУЛ“ (стр. 10). Жестока корица на Моника Вакарелова.
Морска буря. Капитан, който крещи на пътниците да се приберат по каютите – за тяхна собствена сигурност, разбира се. Пътниците обаче очакват да се обърне към тях поименно, а капитанът се чувства неловко със своите заповеди.
Маслен нос е собствено име, име на куче. Хора, куче, море – тази книга има заготовката на приключенски роман, на романите от нашето детство,
тя мирише на водорасли, на потънали гемии, на паламуд, на корморан, на кит, на несвойствена и некотловинна жажда по неежедневния живот.
Маслен нос е впрочем единственото име в книгата. Останалите персонажи са непознатият, рибарят, капитанът, „аз“ – и „ние“. Какво се крие зад това загадъчно местоимение? Неясното, тъмно, фосфоресциращо „ние“? То явно е пришълец от дълбините на страната, идва загърнато в ямурлук, козяк, после шляпа с джапанки, постоянно губи ориентир между севера и юга, лашка се сред светещия планктон, посреща стъписано мъртъв рак, мъртъв делфин, кит, бомба, войната оттатък, към Одеса – и ги приема като предопределение. Като камък, който е бил хвърлен, а днес се връща към теб, без алиби.
Привидната невинност на летуващото „ние“ започва да лъха на „Повелителят на мухите“. И на Шон Тан с неговата чудовищна акула, из чиито недра продължават да излизат все по-малки и по-многобройни чудовища. И тук от разпорения паламуд излиза сафрид, от сафрида – хамсия, от хамсията обаче излиза празнота. Човешката война с природата е завършила с победа – и тази победа е мъртва. Бих казала, че това е една от редките нови български книги, в които отеква толкова ясно болезненият отлив на природата.
Освен че пише поезия, Албена Тодорова е и от най-интересните и непринудени водачи към поезията у нас; Viber каналът ѝ „Поезия на крак“ е разнообразен и точен в избора си; със сигурност ще срещнете неща, на които не сте попадали преди. Литературните ѝ разходки не са екскурзоводски, а перипатетически – имат характера на разговор по време на вървене, на задълбочаване в движение. През нейното литературно любопитство открих и блога на Мария Вирхов, а там – потресаващо стихотворение на Манделщам с призив да оставим хляба в унилите, забравени гори, защото ще дойдат нечакани, неканени гости. На пръв поглед стихотворението напомня за варварите на Кавафис, само че злокобното предчувствие се усилва, чувстваме погрома, който носят със себе си тези гости – докато във финалния стих не разбираме, че те са нашите деца. Става още по-страшно, особено като имаме предвид какво правят „децата на революцията“ със самия Манделщам, когато пристигат.
Бруталното, гледано в упор – това е и усещането при четене на „Дървеният костюм“ на Йордан Д. Радичков.
Абсурдистка сатира в духа на големите източноевропейски образци, книгата всъщност е и смущаващо директна, натуралистична дори в представянето на определени мисловни нагласи. Литературата често говори за емпатия, защото е основана на нея, на съпричастието ни към героите. А тук текстът ти казва директно: „съпричастие друг път“, огледай се, така ли щяхме да живеем, ако на хората действително им пукаше едни за други. Това не е отказ от милост, не е безсърдечие, не е безчувственост – тези думи съдържат в себе си своята противоположност, сякаш съществуват в опозиция с нея.
В книгата обаче „вълчето начало“ е само по себе си, малко подобно на „носорозите“ у Йонеско. То изниква навсякъде по пътя на двамата главни герои, има свой глас, който звучи все по-близо до тях. Дали ако го приемем за естествено, самородно състояние на немалка част от човечеството, няма да ни е по-лесно да разберем и нахлуващите по Манделщам „гости“?
Героите нямат проблем да го направят. Нещо повече, присъствието на смъртта под формата на вкочанения странник е съвсем в реда на нещата, за тях то е практически, а не метафизически проблем. Човешкият смисъл – като да провериш дали някой не познава покойника – става дразнеща, досадна формалност, която пречи на живите.
Здравословна адаптация – или нормализация на чудовищното?
Прочетете книгата, прочетете последните новини и решете. След историята за детето, преседяло часове наред с мъртвото тяло на баща си, защото никой от съседите не искал да му помогне, като звънне на 112, може би тези литературни редове ще се окажат класически реализъм. А не-четенето на уж „абсурдистка“ литература – бягство от действителността.
Поне авторът застава между тези писатели, които посрещат страховитото със смях. Това си личи и от подбора на заглавията в неговото издателство „Нике“ (което неотдавна издаде и „Маус“ на Арт Спигелман, и Булгаков, и Гомбрович), и от страниците на неговите книги. Ако поезията е „къща“, то смехът какво е? Буря срещу бурята.
Активните дарители на „Тоест“ получават постоянна отстъпка в размер на 20% от коричната цена на всички заглавия от каталозите на „Жанет 45“, „Ерго“, „Кота 0“ и няколко други български издателства в рамките на партньорската програма Читателски клуб „Тоест“. За повече информация прочетете на toest.bg/club.
В емблематичната си колонка, започната още през 2008 г. във в-к „Култура“, Марин Бодаков ни представяше нови литературни заглавия и питаше с какво точно тези книги ни променят. Вярваме, че е важно тази рубрика да продължи. От човек до човек, с нова книга в ръка.
From smart devices to workplace tools, AI is becoming part of everyday life and a major part of how people are thinking about the future — raising big questions about access, skills, and readiness.
As governments around the world create AI strategies for the decade ahead, many are seeing an urgent need to address the large gap between how AI tools are already impacting jobs and people’s lives, and making sure young people have the chance to gain the skills and knowledge to keep up with this rapid pace of technological change. This gap is larger still when it comes to opportunities for educationally underserved communities.
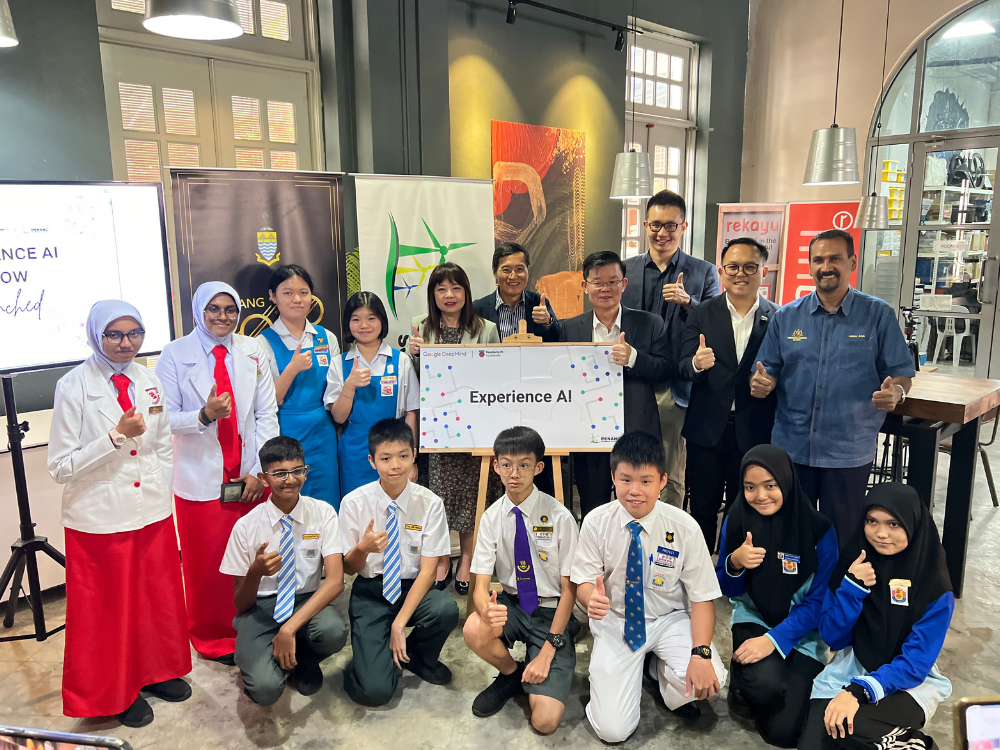
That’s why we’re excited to share how Experience AI, our AI literacy programme, is helping organisations around the world create these much-needed opportunities for young people.
The value of a global network
Experience AI was co-developed in 2022 by us and industry experts at Google DeepMind with a clear mission: to equip teachers with free, accessible, easy-to-use classroom resources that build AI literacy from the ground up. The programme offers a suite of materials to help students understand real-world applications of AI, the basics of machine learning, and the ethical considerations around these technologies.
In 2023, we started building an international Experience AI network by collaborating with a group of our existing educational partners. We saw a huge amount of interest and received very positive feedback, and through our partnerships we reached an estimated one million young people. In late 2024, with support from Google.org, we tripled the size of our Experience AI partner network to 21, with new organisations joining from across Europe, the Middle East, and Africa. In this way, we aim to reach an additional 2.3 million young people by December 2026, helping them to gain the knowledge and skills to confidently engage with AI in an ever-changing world.
Each partner in the Experience AI network is a unique educational organisation looking to create lasting social change. Through their local knowledge and networks, we can present Experience AI to educators and students in a way that is engaging and relevant for local communities.
Partners help us to adapt and translate our resources, all while making sure that the core pedagogy and design principles of Experience AI are preserved. Just as importantly, these organisations train thousands of teachers on how to use the materials, providing educators with free support. With their work, they reach communities that otherwise may have never had the opportunity to learn about AI.
We asked some of our partners to share their insights on the impact Experience AI is having on the teachers and young people in their communities.
Building communities
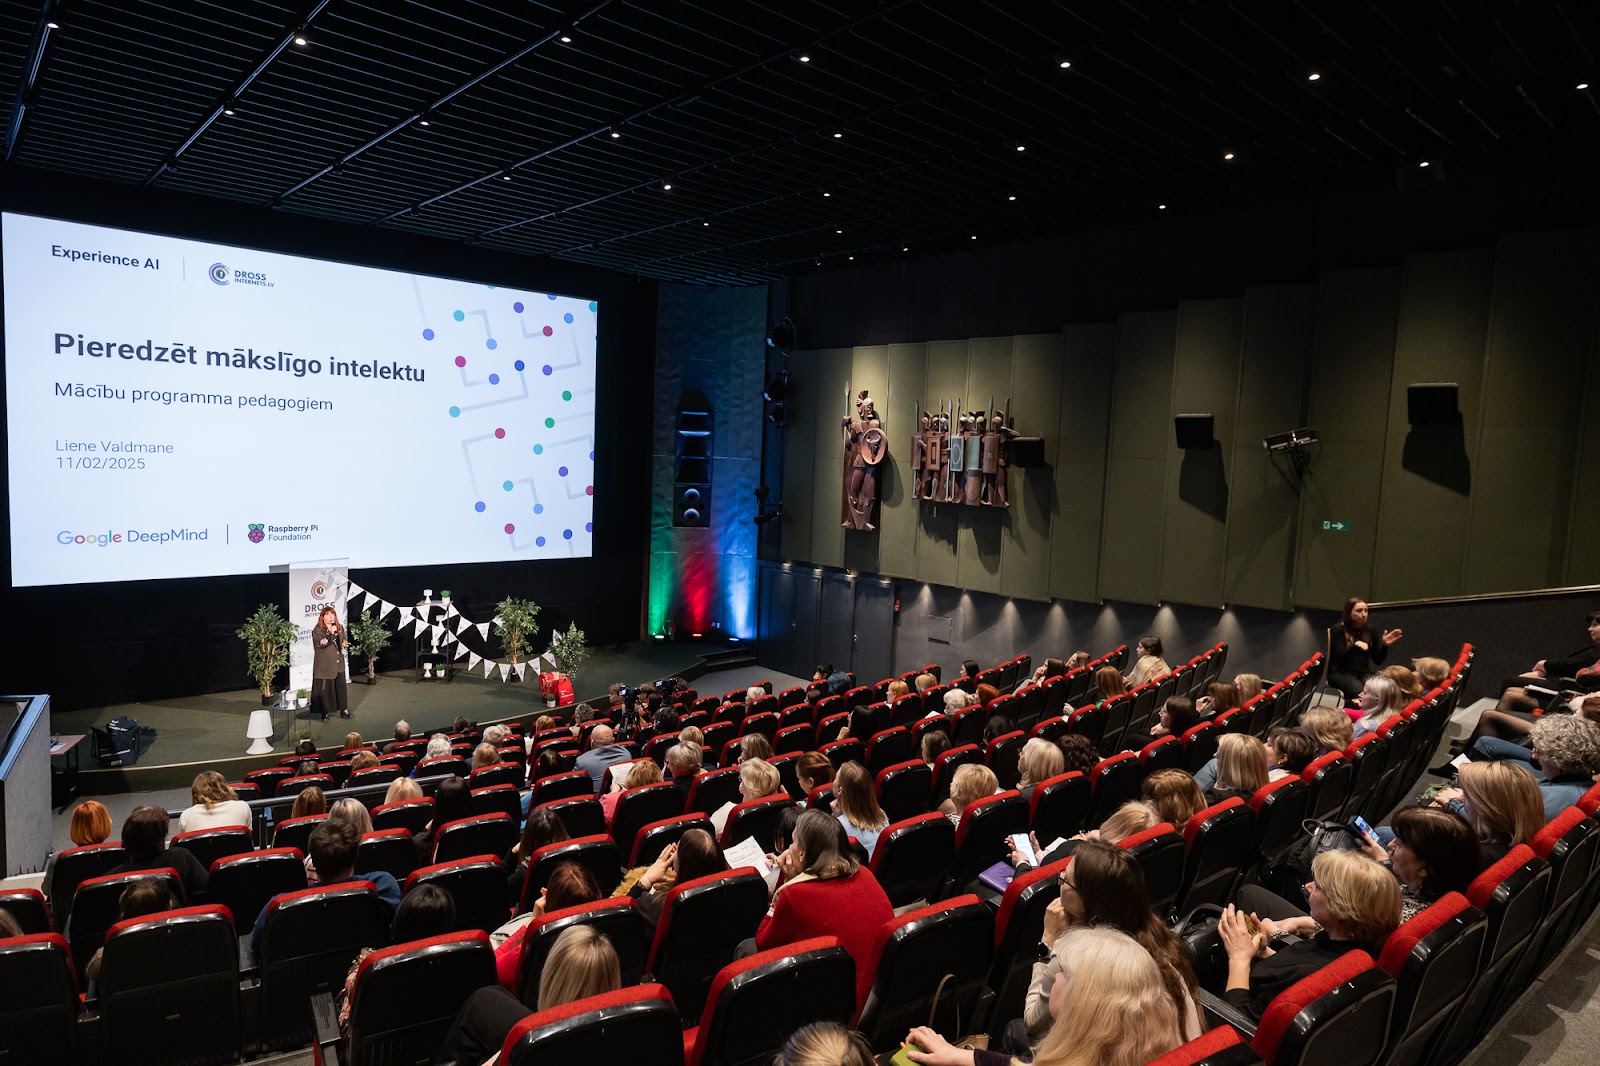
The Latvian Safer Internet Centre (LSIC), an initiative of our partner, the Latvian Internet Association (LIA), is dedicated to helping young people protect themselves online, and to preparing them for a fast-changing digital economy. As an Experience AI partner, they aim to train 850 teachers and support 43,000 students to build a strong foundation in AI literacy through the programme.
“We hope to spark a cultural shift in how AI is […] taught in Latvian schools. Our goal is for AI literacy to become a natural part of digital competence education, not an optional extra.”
Based in Riga, the team is travelling to 18 different regions across Latvia to bring in-person professional development to teachers, including those in rural communities far from major cities. By meeting teachers where they are, the LIA are creating invaluable networks for learning and support between communities. Through hands-on training, they are also supporting teachers to bring Experience AI into their own classroom, creating examples which are suited for their learners.
“We chose an in-person training model because it fosters a more collaborative and engaging environment, especially for teachers who are new to AI. Many educators, particularly those who are less confident with digital tools, benefit from direct interaction, real-time discussions, and the chance to ask questions in a supportive setting.”
As an Experience AI partner, the Latvian Internet Association is not just delivering content but working to strengthen digital competency across the country and ensure that no teacher or student is left behind in Latvia’s AI journey.
One teacher shares: “The classroom training was truly valuable: it gave us the chance to exchange ideas and reflect on our diverse experiences. Hearing different perspectives was enriching, and I’m glad we’re shaping the future of our schools together.”
“AI is for everyone”
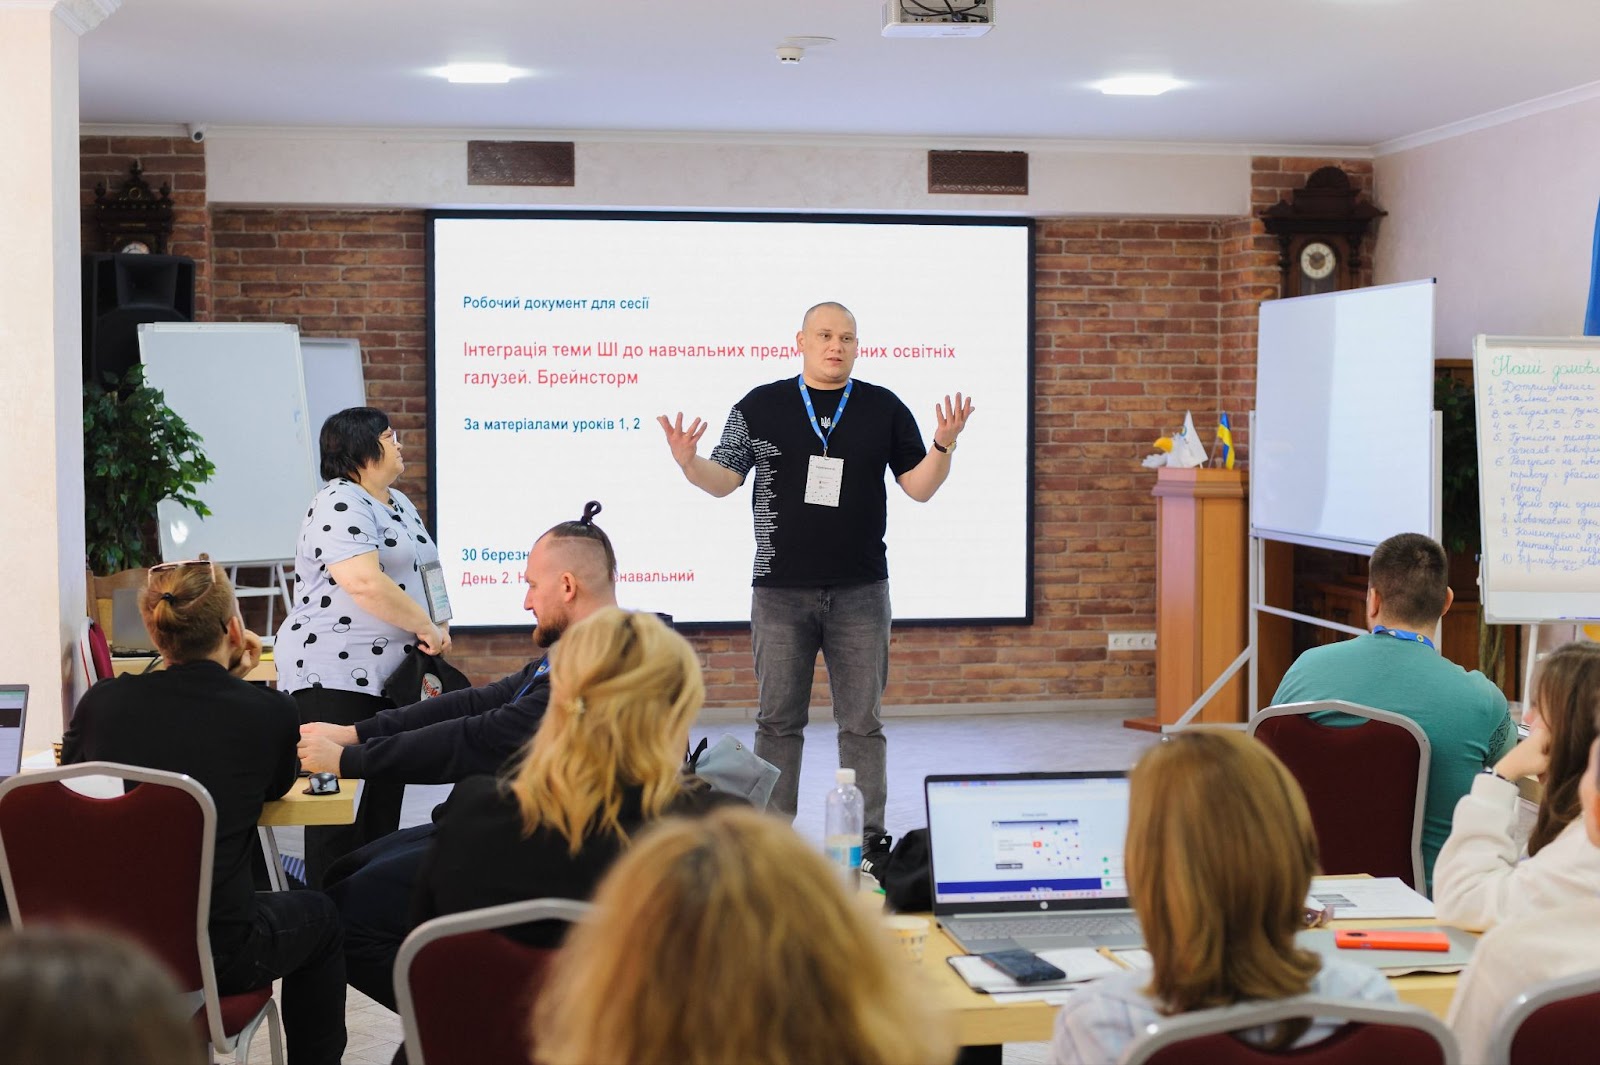
EdCamp Ukraine’s mission is to unite educators and help them to grow. Operating from their main base in Kharkiv, near the Eastern border and the frontline of the ongoing war in Ukraine, they see AI as both a tool for new technological breakthroughs and as something that can help build a fairer, more efficient, and resilient society.
“We firmly believe AI should not only be an object of study — it must become a tool for amplifying human potential. AI should also not be a privilege, but a resource for everyone. We believe the Experience AI programme can truly transform education from the bottom up.”
Within their community of 50,000 teachers, EdCamp Ukraine ensures that every educator, regardless of their living conditions or where they work, can access high-quality, relevant, and accessible support. For the organisation, the ongoing situation in Ukraine means being flexible with planning, preparing for a range of different outcomes, and being ready to pivot delivery to different locations or to an online setting when needed. These same considerations apply to EdCamp Ukraine’s teacher community, who need to be ready to adapt their lessons for any scenario.
“Recognising these war-related challenges helps us see the bigger picture and always have contingency plans in place. We think ahead and develop flexible scenarios.”
This year, the team piloted Experience AI through their community of trainers, who, when they’re not training, are busy teaching in the classroom. Teacher Yuliia shared how her students valued the opportunity to be creators, rather than just users of technology:
“One student, who is an active AI user, kept silent during the lesson. I thought he wasn’t interested, but during the reflection he shared a lot of positive feedback and expressed his gratitude. Other students said it was important that they weren’t just told about AI — they were using it, creating images, and working with apps.”
EdCamp Ukraine plans to roll out training for Ukrainian teachers this autumn, reaching 2,000 teachers and 40,000 young people by the end of next year.
More countries, more classrooms
Two new partners in Nigeria are about to join the Experience AI network, and there are many more organisations in more countries coming soon. As our partner network continues to grow, we are excited to reach more communities and give more young people around the world the chance to build AI literacy skills and knowledge.
You can find out more about Experience AI on the website. If your organisation is interested in partnering with us to deliver Experience AI, please register your interest and we will let you know about opportunities to work with us.
някои спомени са като мумии на диктатори изискват постоянна грижа – разбуждане обработване с химикали ограничаване на туристическите посещения
пазиш ги в гардеробите – тези мавзолеи на култа към преходното – където се разпадат и старческите петна печелят битката с грима
накрая все пак ги погребваш но не спираш да си повтаряш: за мъртвите цялата истина иначе се събуждат
Виолета Кунева
Виолета Кунева е завършила право в СУ „Св. Климент Охридски“. През 2019 г. е публикувана дебютната ѝ стихосбирка „Почти всичко е наред“ (ИК „Жанет 45“), която същата година е отличена с Националната награда за поезия „Иван Николов“ за дебют, а през 2020 г. става лауреат на Националния конкурс за дебютна литература „Южна пролет“. Втората ѝ книга – „Кучето на Персефона“ (ИК „Жанет 45“), е носител на литературната награда „Перото“ в категория „Поезия“ за 2023 г. Виолета Кунева има публикации в сайтове, издания за литература и антологии, участва в литературни фестивали и формати. Стихотворенията ѝ са преведени на английски, испански, хърватски, турски.
Според Екатерина Йосифова „четящият стихотворение сутрин… добре понася другите часове“ от деня. Убедени, че поезията държи умовете ни будни, а сърцата – отворени, в края на всеки месец ви предлагаме по едно стихотворение. Защото и в най-смутни времена доброто стихотворение е добра новина.
Адвокат Даниела Михайлова ръководи правната програма на сдружение „Инициатива за равни възможности“. Тя работи по стратегически дела, свързани с етническата дискриминация. През последните години фокусира професионалните си усилия върху жилищните права на ромите в България, правната помощ за деца от ромски произход в риск и техните семейства, както и върху речта на омразата. Работи и по законодателни приложения за привеждане на националното право в съответствие с европейското и международното.
Дора Петкова е завършила социология и работи в областта на политиките за социално включване, общностно развитие и развитие на гражданското общество. Тя е консултантка, изследователка и работи на терен по национални и международни програми и проекти, насочени към ромската общност. Членува в Етичната комисия на Сдружение „Национална мрежа на здравните медиатори“ и е програмна координаторка във Фондация „Тръст за социална алтернатива“.
Даниела: Служебният адрес се въведе с изменения и допълнения в Закона за гражданската регистрация (ЗГР) от октомври 2024 г. и представлява адрес на имот, който е общинска собственост. Определя се от кмета на всяка община и на него служебно се извършва регистрация по постоянен и настоящ адрес за хора, които не отговарят на условията да бъдат адресно регистрирани по реда на чл. 92 от ЗГР. Важно е да го има, тъй като постоянният адрес е реквизит от личната карта. И ако човек няма такъв, съответно не може да сe издаде документ за самоличност.
Кои са хората, които срещат трудности с адресната регистрация?
Даниела: Непритежаващите документ, който легално ги свързва с адреса на имота, където желаят да извършат адресна регистрация, и документ за собственост или друг, даващ им правно основание да обитават имоти за жилищна нужда. Например договор за наем, ако обитават жилище, което не е тяхна собственост, или договор за ползване на социална или интегрирана здравно-социална услуга. Последното се въведе в ЗГР през 2019 г. с приемането на Закона за социалните услуги.
ЗГР позволява хората, които не могат да представят документ, свързващ ги с имота, да преминат през процедура с разглеждане на заявлението им от комисията по адресна регистрация. Тя, мисля, следва да направи посещение на място, за да установи обстоятелствата, описани в заявлението, и да даде становище за извършване на регистрация по постоянен или настоящ адрес.
Проблемът е, че до февруари тази година правомощията на комисиите по адресна регистрация, които се създават със заповед на кмета във всяка община, не бяха ясно регламентирани. Не беше разписано и какви документи следва да приеме комисията, за да даде становище за извършване на адресна регистрация. Поради тази причина процедурата по чл. 92, ал. 8 от ЗГР беше на практика неработеща.
Затова страшно много хора останаха без регистрация по постоянен адрес – понеже има изискване адресът, посочен в заявлението, да е част от Националния класификатор на настоящите и постоянните адреси на Република България. Той се поддържа от Главна дирекция ГРАО към Министерството на регионалното развитие и благоустройството и обединява в една база данни всички настоящи и постоянни адреси, подавани от кметовете на общините, защото те са тези, които решават на кои адреси в тяхната община може да бъде извършена адресна регистрация.
Наредбата, издадена от регионалния министър, уточнява на какви условия трябва да отговаря един адрес, за да бъде включен в Националния класификатор – на него трябва да има постройка, годна за обитаване.
Проблемът е, че в голямата си част кметовете на общините, така да се каже, самодопълват изискването на наредбата, като търсят на адреса да има законно изградена постройка – условие, което липсва и в ЗГР. Поради това доста адреси бяха заличени и извадени от Националния класификатор.
И ако едно лице живее на такъв адрес – в незаконна постройка, – то не може да бъде адресно регистрирано.
Що се отнася до хората без лични документи, направихме проучване по реда на Закона за достъп до обществена информация чрез заявления до МВР, първото от които подадохме през 2021 г. Отговорът на Вътрешното министерство беше, че по техни данни в България има около 122 000 души без валидна лична карта и други 120 000, на които никога не е издаван документ за самоличност, макар да са навършили възрастта за това.
В тази бройка, разбира се, влизат и дългогодишни емигранти, някои от които вече са граждани на други държави. Тоест много от тях може и да нямат интерес да притежават българска лична карта. Но се оказва, че малко повече от 75 000 български граждани, живеещи на територията на страната, нямат документ за самоличност, макар че са навършили възрастта за това. Става въпрос преди всичко за хора в уязвимо положение. Те или нямат документ за собственост на къщите, в които живеят, или изобщо по никакъв начин не могат да докажат връзка с адреса си.
Този проблем възникна през 2011 г., когато с промените в Изборния кодекс беше изменен и ЗГР – въведе се изискването да се представя документ, който сочи връзка с адреса. Преди това режимът за издаване на постоянен и настоящ адрес беше свободен – трябваше само да се подаде заявление, без да се изискват допълнителни документи.
Дора Петкова и Даниела Михайлова. Снимки: личен архив
Какво означава за един човек да няма документи за самоличност? И какво е да се родиш без документи?
Дора: Всъщност съвсем наскоро с Даниела имахме такъв случай. Работим заедно по проект на „Тръст за социална алтернатива“, който се нарича „Мрежа с грижа от 0 до 3. Превенция на разделяне на семействата“. Той включва мрежа от 11 неправителствени организации, които работят на терен с уязвими общности в цялата страна. Затова от години си сътрудничим по места с медиатори и с общностни работници. Тази мрежа има четири компонента. Единият е осигуряване на достъп до безплатни лекарства за деца от 0 до 7 години. Вторият е осигуряване на хранителна подкрепа под формата на ваучери за деца в уязвимо положение. Третият компонент включва въвеждането на нови стандарти и координационни подходи в работата по превенция на разделяне на семействата. Последният компонент е свързан с липсата на лични документи и адресни регистрации – неравенство за много граждани, което се опитваме да преодолеем чрез прилагането на новите изменения в закона.
Във всички населени места, в които работим, здравните медиатори и общностните работници се стремят да помогнат на хората без лични документи. И така в Ямбол открих група бивши обитатели на съборения блок 20, за който всички си спомняме.
Дора: Очевидно е, че те не е имало къде да бъдат настанени, и са останали без дом. Не знам дали някой знае – или по-точно дали се интересува – какъв е техният брой, вероятно е между 30 и 50 души. Но по-голямата част от тях нямат адресна регистрация, нямат лични документи от 10 години. Срещнахме млада майка с дете на една година, която няма личен документ, съответно детето не притежава удостоверение за раждане, няма личен лекар, имунизации, достъп до здравни и социални грижи, до детска градина, по-нататък до училище и всичко останало, което би трябвало да се полага за пълноценното развитие на всяко дете.
Така че ето как, когато нямаш личен документ, ти си лишен от първия си ден от достъп до основни човешки грижи и права. Дано предотвратим това да се случи и с децата и техните семейства от „Захарна фабрика“, които съвсем скоро останаха без дом. Нали твърдим, че децата са най-ценни?
Такова дете ще може ли да тръгне на училище, майка му ще може ли да получава детски надбавки?
Дора: Има различни случаи, повечето от които много сложни. Понякога хората имат някаква регистрация, но тя е в друго населено място – примерно майката се е преместила. Но ако тя не може да се регистрира на новия си адрес, например защото той не е в Националния класификатор на адресите, трябва да остане с предишния си и детето няма как да бъде записано в детска градина. Когато родителите нямат личен документ, как едно дете да бъде записано в детска градина или в училище? Как и къде да работят родителите?
Здравните медиатори, разбира се, се опитват да помагат. Ние с Даниела се срещаме с отделите на МВР по места, с представителите на общините, на ГРАО, за което благодарим. Преди дни участвахме в такава среща в Казанлък. Там се бяха събрали представители на местни институции от съседни градове с подобни проблеми. Конкретно за Ямбол срещнахме подкрепа, но се оказа, че е необходимо хората, които от години живеят без лични документи, да бъдат идентифицирани, за което вече помагат отново медиатори и активни граждани от общността. Силно се надяваме заедно с местните институции този проблем да се разреши по-скоро.
Оказва се, че законът ненавсякъде се прилага по един и същи начин, затова е необходимо да се унифицира.
Така стигнахме до следващия ми въпрос: как се осъществява издаването на служебни адреси след промяната на закона и какви са основните проблеми? В началото изглеждаше, че всичко ще потече по мед и масло, но явно не е точно така.
Даниела: Има някои случаи, в които промяната в закона се оказва недостатъчна. Става въпрос преди всичко за хората, на които не е издаден документ за самоличност, когато са били между 14- и 18-годишна възраст. При издаването на първа лична карта непълнолетното лице се придружава и съответно се идентифицира от родителите си. Ако това не се направи в този период, после идентификацията трябва да се извърши от органите на МВР. Тоест те трябва да бъдат сигурни, че човекът, който подава заявлението, е същият, на когото ще бъде издадена личната карта. И тук вече настава известен хаос, защото по принцип полицаите извършват тази идентификация, като правят посещение на постоянния адрес и събират данни от съседите. Обаче лицето не е длъжно да живее там. Така че МВР не може да извърши идентификацията по постоянен адрес.
Тогава се забавят всякакви видове процедури, защото, когато полицаите откажат да извършат идентификацията, издаването на лични карти се „закучва“. Защото човек не може да промени адресната си регистрация, преди да има документ за самоличност, който да представи в общината. Та поради тази причина няма как да бъде издадена лична карта. Получава се нещо като параграф 22.
Истината е, че служителите на полицията могат да извършват тази идентификация и в районните управления по места, където се подава заявлението за издаване на лична карта. Днес минахме през такава процедура с една млада жена, на 24–25 години. Тя е в напреднала бременност, тоест издаването на личната карта беше спешно. От Дирекция „Български документи за самоличност“ на МВР ни казаха да отидем при тях, а не в РПУ-то. Изглежда, им се видя по-лесно директорите сами да си свършат работата, отколкото да обяснят на полицаите в РПУ-тата.
Само че това реши единствено конкретния въпрос: жената ще си получи личната карта във вторник. Но не решава генералния въпрос, понеже не е само тя – този случай е повторяем. Според мен е необходимо да се издаде някаква инструкция, защото не можем да водим всеки човек в такава ситуация в дирекцията. Трябва да има процедура.
Дора: Този казус продължи доста дълго, доколкото знам – няколко месеца.
Даниела: Ами да, продължи, докато в крайна сметка не се свързахме с Министерството и не им казахме: „Добре, разпоредете писмен отказ, за да можем да го обжалваме.“ Тогава те отговориха: „Не, елате в дирекцията.“
Дора: Всъщност всички много се плашат от писмените документи. Институциите – от писмени откази, а хората – от подаването на писмени заявления и жалби.А за да бъдат променени по-лесно юридическите практики, би трябвало и институциите, и гражданите да съдействат. Но нито гражданите, поне според моите наблюдения, нито администрацията разбират това. Струва ми се, все още нямаме гражданската култура и не осъзнаваме, че това са демократичните инструменти, които биха улеснили промяната на закони и други актове в полза на обществото. В България това все още не се случва.
Хората искат промяна, но със или без причина, се страхуват сами да я осъществяват.
Има още едно препятствие, по-скоро противоречие, което обсъдихме по време на срещата с институциите в Казанлък. Оказва се, че ако човек е регистриран на служебен адрес, то много трудно може да получи социална помощ.
Защо?
Дора: Защото от Агенцията за социално подпомагане трябва да отидат на този служебен адрес – по закон те трябва да посетят лицето и да видят къде живее, има ли нужда от социална помощ.
Даниела: Прави се социална анкета по настоящ адрес.
Дора: Да, но понякога те не знаят или пък не желаят да се задълбочават и да търсят къде живее този човек. Законът им позволява да откажат.
На нашите институции им предстои да работят заедно, за да синхронизират нормативните документи. Защото моите колеги от 11 години работят за въвеждането на служебен адрес, така че повече хора да имат лични документи, да няма деца, лишени от права, да се преодоляват бедността и неравенствата. Но се оказва, че това би могло да затрудни, вместо да улесни достъпа до социални, здравни услуги и т.н. за най-уязвимите и бедни хора. А идеята на изменението в закона е документът за самоличност да послужи за преодоляване на проблемите, свързани с бедността и социалното изключване, в нашата европейска държава.
На практика без лични документи си абсолютно изключен. Разполагаме дори с информация за хора, които толкова са свикнали да живеят по този начин, че даже се плашат да имат лични документи.
Има много деца, които живеят в бедност в различни махалички, селца и т.н., с които не знаем какво се случва.
Според Вас какво трябва да се направи и на законодателно равнище, и като практика, за да се решат тези проблеми?
Дора: Ние в момента правим това по съвместния ни проект. Даниела обучава 300 души – здравни медиатори и общностни работници, които работят на терен в своите общности – да прилагат закона на практика. Между другото, към тях започнаха да се присъединяват и представители на местни институции. Това е процес, който е съвсем в началото, и в него срещаме всички тези истории и трудности, за които разказваме сега. Надяваме се, че ще има напредък. По този начин провокираме местните институции да стигат до извода, че има нужда от още промени, за да се случат нещата. И макар че процесът е труден и бавен и се отключват и появяват – понякога дори зейват – още проблеми, има смисъл да се работи, да се подобряват законите и разбирането по тези толкова неглижирани и дълго премълчавани въпроси. Необходима е работа на терен и с институциите.
Важно е да се осъзнае, че ще е от полза за цялото ни общество повече хора да имат документи за самоличност и адресни регистрации. Това означава, че повече хора ще имат права, но ще имат и задължения. Ще могат да работят, да учат, децата им ще бъдат по-здрави и по-образовани. А хората от най-уязвимите групи, най-бедните, най-маргинализираните, много често унаследяват тази бедност и я предават нататък, на децата, през поколенията. Опитваме се да прекратим този порочен кръг, макар да не е лесно.
Front: Glibc security; How we lost the Internet; Encrypted DNS; 6.15 Development statistics; Filesystem stress-testing; BPF verifier; Network access from BPF; OSPM 2025.
This is the NVIDIA MGX PCIe Switch Board with ConnectX-8 for 8x PCIe GPU servers, marking the most significant architectural shift in a decade in this segment
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


 Steven Aerts is a principal software engineer at Airties, where his team is responsible for ingesting, processing, and analyzing the data of tens of millions of homes to improve their Wi-Fi experience. He was a speaker at conferences like Devoxx and AWS Summit Dubai, and is an open source contributor.
 Reza Radmehr is a Sr. Leader of Cloud Infrastructure and Operations at Airties, where he leads AWS infrastructure design, DevOps and SRE automation, and FinOps practices. He focuses on building scalable, cost-efficient, and reliable systems, driving operational excellence through smart, data-driven cloud strategies. He is passionate about blending financial insight with technical innovation to improve performance and efficiency at scale.
 Ramazan Ginkaya is a Sr. Technical Account Manager at AWS with over 17 years of experience in IT, telecommunications, and cloud computing. He is a passionate problem-solver, providing technical guidance to AWS customers to help them achieve operational excellence and maximize the value of cloud computing.