Application security at re:Inforce 2025

Post Syndicated from Daniel Begimher original https://aws.amazon.com/blogs/security/application-security-at-reinforce-2025/

AWS re:Inforce 2025: June 16-18 in Philadelphia, PA

A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.

Join us in Philadelphia on June 16–18, 2025, for AWS re:Inforce, where you can enhance your skills and confidence in cloud security, compliance, identity, and privacy. As an attendee, you will have access to hundreds of technical and non-technical sessions, an Expo featuring Amazon Web Services (AWS) experts and AWS Security Competency Partners, and keynote sessions led by industry leaders. AWS re:Inforce offers a comprehensive focus on key security areas, including application security (AppSec).

Key AppSec themes for 2025

The AppSec track helps you understand and implement best practices for securing your applications throughout the development lifecycle. For 2025, we’re focusing on several key themes:

Organizational strategies to ship quickly and securely

Learn about security ownership, partnerships like DevSecOps, comprehensive application security programs, and scaling application security expertise into workload teams. These sessions explore how organizations can build security into their development processes without sacrificing speed, focusing on practical approaches that distribute security responsibility effectively.

Secure by design

Make embedding security principles into the early stages of software architecture and design to mitigate vulnerabilities early, minimize risks, and recognize security as a core business requirement. Learn how leading organizations implement security as a foundational element rather than an add-on consideration.

Security of the pipeline

Security of the pipeline includes tooling, reference architectures, and best practices for securing the pipeline, including Supply chain Levels for Software Artifacts (SLSA), Supply Chain Integrity, Transparency, and Trust (SCITT), and code signing. Discover how to protect the systems and processes that build and deploy your applications.

Security in the pipeline

Security in the pipeline is achieved in part through testing methodologies including static analysis, dynamic analysis, responsible AI testing, software composition analysis, formal methods (automated reasoning), and dependency tracking. These sessions demonstrate how to integrate comprehensive security testing throughout your development lifecycle.

In the following sections, you’ll find a subset of some of the most exciting sessions happening in our AppSec track this year. For the full list, visit the re:inforce 2025 catalog.

Breakout sessions, chalk talks, lightning talks, and code talks

APS204 | Breakout session | Scaling security with Sportsbet’s Security Guardians program
The Security Guardians program helps scale security across application teams by building and embedding security expertise. We dive deep on Sportsbet’s program where you will learn how to get started, key phases to consider, and the first learning steps for new guardians. Discover lessons learned, common challenges, and how to refine the program for long-term success. By integrating security into application teams early, Sportsbet fosters a culture of shared responsibility, improving security posture without slowing down development. We provide practical insights on launching and evolving a Security Guardians program to drive real impact across your organization.

APS301 | Breakout session | Improve code quality with Amazon Q Developer
Amazon Q Developer is a generative AI assistant that goes beyond writing code—it can also improve documentation, generate unit tests, and automate code reviews. In this session, discover how to integrate Amazon Q Developer into your software development lifecycle to detect security issues using software composition analysis (SCA), static application security testing (SAST), and other code quality checks. Learn how to improve your codebase quality using the capabilities of Amazon Q Developer within the integrated development environment (IDE) and DevSecOps tooling.

APS401 | Breakout session | Build verifiable apps using automated reasoning and generative AI
Large language models (LLMs) excel at generating creative solutions, while automated reasoning tools enable rigorous verification. This session explores methodologies for combining these complementary strengths to create more reliable AI systems. In this session, we introduce automated reasoning and demonstrate how formal methods can guide and constrain generative AI. By combining probabilistic and symbolic approaches, we show you how to build hybrid systems that maintain creative capabilities while ensuring verifiable outputs. We demonstrate how Amazon Q Developer and Amazon Bedrock Guardrails use automated reasoning to generate safe and logically correct output, free from hallucinations.

APS431 | Chalk talk | DevSecOps in action with Visual Studio Code & AWS IAM Access Analyzer
Organizations face a critical balance between developer productivity and security compliance when managing AWS Identity and Access Management (IAM) policies. In this session, discover how integrating AWS IAM Access Analyzer with Visual Studio Code empowers developers to create secure IAM policies during development. Learn to implement automated policy checks that catch overly permissive permissions early, validate against organizational standards, and provide real-time feedback. This proactive approach helps security teams maintain control while giving developers the autonomy they need, ultimately reducing deployment risks and saving valuable development time.

APS341 | Code talk | Move fast and stay secure: Lessons learned from the AWS prototyping team
When building prototypes and applications with technologies such as generative AI and serverless, it’s critical to move quickly and securely. In this code talk, learn how the AWS prototyping team successfully balances these goals. To meet user demand, AWS builds prototypes over a short amount of time while meeting a high bar for security expectations. Learn pointers, tips, and tricks to build quickly and securely, from threat modeling to using AWS Cloud Development Kit (AWS CDK) features, custom constructs, and blueprints to harden the security of your infrastructure and improve productivity.

APS441 | Code talk | Supercharge IaC security with AI: From commit to auto-remediation
Dive deep into building an automated security feedback loop that combines Git commit signatures, static analysis, and generative AI to revolutionize infrastructure as code (IaC) security. Through live coding, we’ll demonstrate how to use Amazon Q Developer and Amazon Bedrock to analyze IaC templates, automatically detect and resolve issues, and generate contextual fix recommendations. Learn how to implement commit-based tracking for security findings, automate issue creation, and integrate with continuous integration and delivery CI/CD pipelines. Watch as we build a complete system that reduces the time from vulnerability detection to remediation from days to minutes.

APS442 | Code talk | Create memory safe applications using open source verification tools
Memory-safety errors pose a significant security risk, enabling various attack vectors. At AWS, we prioritize memory-safety for unmanaged code handling customer data and processes. This talk presents two efforts to reduce memory-safety errors in Rust and C code. Both efforts involve developing verification tools for Rust and C code to check memory safety at scale that you can use. Our first effort verifies the Rust standard library, a core software resource, used by millions of developers. Our second effort uses a C model checker to verify C code for safety and correctness.

APS221 | Lightning talk | Building secure development into Amazon stores
Amazon.com has long been at the forefront of investing in robust security measures to protect customer data. As the digital landscape evolves, so do our strategies. This session explores our journey of continuous improvement in security practices, focusing on integration throughout the software development lifecycle using AWS services. We’ll share the cutting-edge methods used by Amazon.com for embedding security at every development stage and discuss successes and learnings. Join us to discover how we’ve adapted our tactics to meet changing developer and customer needs and to ensure our commitment to protecting customer data remains stronger than ever.

APS222 | Lightning talk | Transform threat modeling using generative AI
Discover how CRED, one of the biggest Fintech companies in India has used generative AI to automate threat modeling across their applications. Learn architectural patterns that enabled CRED to scale security analysis, improve risk identification, and enhance decision-making. See practical examples of integrating AI into security modeling workflows using Amazon Bedrock.

SEC221 | Lightning talk | Raising the tide: How AWS is shaping the future of secure AI for all
AI security is a top priority for AWS. By building AI solutions that are secure by design, AWS helps you innovate quickly with confidence while mitigating emerging threats. But securing AI goes beyond individual organizations—it requires industry-wide standards and best practices. AWS actively contributes to global AI security efforts, including participation in industry standards bodies such as The Coalition for Secure AI (CoSAI), to help ensure that AI technologies are safe, resilient, and trustworthy. This session will explore how AWS is leading AI security innovation, protecting customers, and collaborating to help shape the future of AI security for the entire industry.

Workshops and builders sessions

APS351 | Securing generative AI agents using AWS Well-Architected Framework
Learn hands-on how to build secure generative AI agent solutions following the AWS Well-Architected Framework Generative AI Lens security best practices. Work through practical implementations of endpoint security, prompt engineering guardrails, monitoring systems, and protection against excessive agency while building a production-ready generative AI agent. Through hands-on exercises, build a secure generative AI agent solution incorporating these controls on AWS, using Amazon Bedrock, Amazon CloudWatch, IAM, and more. You must bring your laptop to participate.

APS353 | Red-teaming your LLM security at scale
Step into the shoes of an AI-powered red team adversary in the GenAI Red Team Challenge. In this intensive workshop, you’ll deploy an AI security agent to orchestrate sophisticated attack chains against generative AI applications, systematically discovering and exploiting vulnerabilities from prompt injection to boundary testing while mastering automated security testing workflows. In addition, you’ll learn how to apply countermeasures, from prompt templating to guardrails. This hands-on, gamified experience helps you think like a threat actor and equips you with practical skills in automated vulnerability testing and risk mitigation against common MITRE and OWASP vulnerabilities for LLM-based applications. You must bring your laptop to participate.

APS354 | Secure your application using AWS services and open source tooling
AWS, open source, and partner tooling work together to accelerate your software development lifecycle. Learn how to use the Automated Security Helper (ASH), an open source application security tool, to quickly integrate various security testing tools into your software build and deployment flows. AWS experts guide you through the process of security testing locally on your machines and within a simulated pipeline using a sample generative AI application. Discover how to identify potential security issues in your applications through static analysis, software composition analysis, and infrastructure-as-code testing, and use Amazon Q Developer to review the results and generate remediation. You must bring your laptop to participate.

APS271 | Threat modeling for builders
In this workshop, you will learn threat modeling core concepts and how to apply them through a series of group exercises. Key topics include threat modeling personas, key phases, data flow diagrams, STRIDE (spoofing, tampering, repudiation, information disclosure, denial of service, and elevation of privilege), and risk response strategies. We introduce a threat grammar rule and an associated tool. Exercises will have you identify threats and mitigations through the lens of each of the threat modeling personas. You will assemble in groups and walk through a case study. AWS threat modeling subject matter experts will be on hand to guide you and provide feedback. You must bring your laptop to participate.

APS371 | Securing your generative AI applications on AWS
In this workshop, discover how to secure generative AI applications using AWS services and features. Explore how to deploy a vulnerable sample generative AI application and then layer security controls to protect, detect, and respond to security issues. Learn how to apply similar controls to the generative AI applications in your organization. You must bring your laptop to participate.

APS471 | Boost developer productivity with Amazon Q Developer and Amazon Bedrock
Accelerate development and drive innovation with Amazon Q Developer and Amazon Bedrock. Discover how AI-powered automation and intelligent code assistance can reduce friction, speed up development cycles, and improve code quality. Explore real-world use cases such as AI-driven code reviews, automated testing, and smart documentation generation. Learn how to seamlessly integrate these tools into your workflows to boost efficiency, enhance collaboration, and elevate the developer experience—all while making sure of security and compliance. Whether optimizing existing processes or adopting AI for the first time, this session provides actionable insights to supercharge your development teams. You must bring your laptop to participate.

Conclusion

This post showcases a subset of the exciting AppSec sessions available at the upcoming AWS re:Inforce 2025 conference. If you’re interested in these topics, we encourage you to register for re:Inforce 2025, where you can attend these sessions and many more across the other security domain tracks. To discover the full range of sessions across all security tracks, check out the complete AWS re:Inforce catalog.

If you have feedback about this post, submit comments in the Comments section below.

Daniel Begimher

Daniel Begimher

Daniel is a Senior Security Engineer specializing in cloud security and incident response solutions. He co-leads the Application Security focus area within the AWS Security and Compliance Technical Field Community, holds all AWS certifications, and authored Automated Security Helper (ASH), an open source code scanning tool. In his free time, Daniel enjoys gadgets, video games, and traveling.

Danny Cortegaca

Danny Cortegaca

Danny is a Security Specialist Solutions Architect and co-leads the Application Security focus area within the AWS Security and Compliance Technical Field Community. He joined AWS in 2021 and partners with some of the largest organizations in the world to help them navigate complex security and regulatory environments. He loves talking about application security with customers and has helped many adopt threat modeling into their practices.

Enhancing multi-account activity monitoring with event-driven architectures

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/enhancing-multi-account-activity-monitoring-with-event-driven-architectures/

Enterprise cloud environments are growing increasingly complex as they scale, with organizations managing hundreds to thousands of Amazon Web Services (AWS) accounts across multiple business units and AWS Regions. Organizations need efficient ways to collect, transport, and analyze activity data for threat detection and compliance monitoring. This presents unique challenges for enterprise Application Security (AppSec) teams, cloud security vendors, and DevSecOps professionals, because traditional polling-based monitoring approaches struggle to provide real-time activity insights needed for modern cloud operations.

In this post, you will learn to use AWS CloudTrail and Amazon EventBridge for real-time cloud activity monitoring and automated response.

Overview

As organizations expand their cloud footprint, account activity monitoring that comprehensively tracks user actions and successfully identifies security threats becomes crucial for threat detection and compliance. Although AWS provides native tools—such as CloudTrail for API activity capture, EventBridge for real-time event routing, AWS Organizations for multi-account management, and AWS Config for resource evaluation—many enterprises struggle with the volume of activities while maintaining efficiency and controlling costs. Organizations need to carefully architect solutions to effectively use these tools as their environments scale.

Traditional polling-based techniques, which worked well for smaller environments, can become unsustainable when scaled to enterprise deployments, where the volume of activity data grows exponentially with each new account and service. API polling limitations, growing data volumes, and increasing demand for real-time analysis are pushing teams to rethink their architectural approach.

Figure 1. Poll model, periodically retrieving the latest state.

Adopting push-based event-driven architectures offers a compelling solution for AppSec teams and cloud security vendors facing these challenges. Using AWS services, such as CloudTrail and EventBridge, allows these teams and vendors to build scalable activity monitoring solutions that overcome the limitations of traditional polling-based approaches and provide real-time notifications across thousands of AWS accounts. This approach not only enables security use cases but also supports broader real-time operational monitoring, compliance reporting, and automation requirements.

“By integrating AWS CloudTrail and Amazon EventBridge, we’ve built a scalable architecture to monitor activity across thousands of AWS accounts. This provides the visibility needed to detect threats in real time and protect large, distributed AWS environments.” — Rob Solomon, Senior Cloud Solution Architect, CrowdStrike

Solution components

Enterprise AppSec teams and cloud security vendors share common requirements when building multi-account monitoring solutions. They need to efficiently collect activity data across thousands of accounts, transport it to a centralized location for analysis, and process it in real-time to detect threats and compliance violations. The solution must scale seamlessly from dozens to thousands of accounts while remaining highly-performant and cost-efficient. At its core, a scalable multi-account activity monitoring solution consists of three components: activity data collection, cross-account transport to a centralized location, and processing. In the following sections, you will learn how AppSec teams and cloud security vendors can implement each step efficiently while avoiding common pitfalls.

Figure 2. Push model. Account activity is collected at the source, and pushed to the AppSec or cloud security vendor account for further processing.

Data collection strategies

Many teams begin their cloud activity monitoring journey by polling the resource status through service management APIs. Although this approach works good for retrieving the latest resource state on-demand, its fundamental limitation is inability to detect state changes efficiently, necessitating continuous querying of all resources at fixed intervals. Consider a scenario where you’re monitoring 1,000 accounts, with 100 resources in each account. A single polling cycle would necessitate 100,000 API requests, consuming over 28 million API calls daily if running at five-minute intervals. This inefficiency compounds as environments grow, leading to throttling issues, increased costs, and scaling challenges.

AWS Config improved upon this by offering continuous resource configuration tracking without manual polling. Although this works excellent for configuration compliance and a history of changes for auditing, AWS Config reports changes on a best-effort basis and is not optimal for real-time threat detection.

To overcome this constraint, your solution can use services such as CloudTrail and EventBridge as primary data sources, complemented by intelligent on-demand targeted API polling. CloudTrail records API activity across AWS services, providing a detailed history of actions taken by users, roles, and AWS services in your accounts. Over 250 AWS services automatically report their activity and API calls to CloudTrail and EventBridge in real-time. This allows you to capture this information, providing a detailed history of actions taken in your accounts, and enabling security analysis, resource state change tracking, and compliance audit.

Figure 3. Over 250 AWS services are automatically emitting activity events to CloudTrail.

When a resource state changes, commonly as a result of a management API call, the affected service sends an event to CloudTrail and EventBridge. Your monitoring solution can examine the event payload to determine if polling for supplementary data is necessary, particularly when the initial payload lacks complete information. This provides you with comprehensive service coverage with reduced maintenance effort. This hybrid approach guarantees delivery of activity data to eliminate monitoring blind spots, while significantly reducing AWS management API quota consumption.

Cross-account data transport

Your solution should transport activity data from thousands of tenant accounts into a small number of centralized accounts, such as a regional AppSec account, for further processing and analysis. The solution must be secure, scalable, resilient, and cost-efficient while maintaining real-time delivery.

The most direct way to achieve it is to enable Amazon S3 event notifications for new objects that are created in the CloudTrail trails S3 bucket. When you receive the notification, you can retrieve and process new activities.

Figure 4. Exporting CloudTrail events into an S3 bucket and retrieving after receiving a notification.

This direct way to consume CloudTrail events has one important consideration: typically it can take an average of five minutes to deliver events to Amazon S3. Teams and vendors looking for lower mean-time-to-detect (MTTD) and mean-time-to-respond (MTTR) should evaluate transporting CloudTrail events across accounts with EventBridge, which provides close-to-real-time delivery.

Transporting events with EventBridge

EventBridge is a serverless event router that connects applications. It receives events from various sources, such as CloudTrail, and routes them to multiple targets based on defined rules.

Using EventBridge for cross-account data transport comes with several major benefits:

There are two approaches you can take for delivering cross-account events with EventBridge: direct service-to-service or service-to-API-endpoint.

The first approach uses the EventBridge direct bus-to-bus and bus-to-service delivery capabilities. This method is most suitable when you want AWS to handle data ingestion on the receiving end. The delivery target is always either an EventBridge bus, or another AWS service, such as an Amazon Simple Queue Service (Amazon SQS) queue, Amazon Kinesis Data Streams stream, or an AWS Lambda function. With support for up to 18,750 target invocations per second and native AWS Identity and Access Management (IAM) integration, this method is particularly suitable for large multi-account deployments.

The second approach uses the EventBridge API destinations feature. This method is most suitable when you have existing HTTP-based ingestion endpoints in place. Although it offers lower throughput, it provides greater flexibility for ingestion endpoint and authentication methods implementation, making it attractive for AppSec teams and cloud security vendors integrating with existing ingestion infrastructure.

Figure 5. Emitting CloudTrail events in real-time through EventBridge.

The following table summarizes two approaches for transporting events across accounts with EventBridge.

Direct bus-to-bus or bus-to-service API destinations
Data ingestion implementation effort Minimal Needed
Default target invocations per second (TPS) quotas Up to 18,750 (region dependent) Up to 300 (region dependent)
Can the TPS quota be increased Yes Yes
Authorization support Native AWS IAM, fully handled by AWS Basic, OAuth2, API Key. You’re responsible for implementing credentials validation during ingestion.
Cross-account delivery costs $1 per million events $0.20 per million events

Go to the EventBridge quotas and pricing pages for more details.

Processing architecture

Processing would commonly be done by existing products and services the AppSec team or cloud security vendor provides for activity analysis. The architecture for event processing pipeline operating at enterprise scale must consider design decisions to handle large and potentially irregular event volumes while maintaining high performance, as shown in the following figure.

Figure 6. An activity event processing pipeline, with priority-based processing.

Use the following best practices for a robust processing architecture:

  • Buffer ingested events Use services such as Amazon SQS, Amazon Kinesis Data Streams, or Amazon Managed Streaming for Apache Kafka to buffer incoming events, handle traffic surges, and make sure of reliable processing.
  • Use serverless services that scale automatically, or invest in automated scaling mechanisms that adjust processing capacity based on event volume
  • Minimize polling: Resort to intelligent on-demand polling, only poll when you need additional data that is not available in the CloudTrail event payload.
  • Routing and classification: Rather than processing all events equally, implement intelligent classification and routing early in your pipeline. Security-related events such as IAM changes or security group modifications should take priority over routine activities or data events. This approach helps to control costs while maintaining rapid detection of important security events.
  • Cost optimization: At the enterprise scale, cost optimization becomes crucial. Use EventBridge rules in source accounts to filter out irrelevant events before they enter your processing pipeline. Consider implementing regional collection points to optimize data transfer costs. When using Lambda functions for data processing, use batch processing to reduce invocation costs. Evaluate which event types must be delivered in real-time through EventBridge, which event types can be delayed and collected through S3 bucket export, and which events should be discarded.
  • Observability: Monitor the ingestion and processing throughput to react to potential slowdowns early. Detect when source accounts are approaching EventBridge quotas. Consider using AWS Service Quotas to request quota increases automatically through APIs.
  • Cross-Region considerations: Design your architecture to support efficient cross-Region event collection while respecting data sovereignty requirements. Consider implementing regional processing nodes with centralized aggregation for global security analysis.
  • Integration patterns: Modern security solutions must integrate with existing security tools and workflows. Implement standardized output formats that allow seamless integration with SIEM systems, ticketing platforms, and automation frameworks. Consider publishing security findings back to EventBridge buses to enable automated remediation workflows. If you’re a cloud security vendor, then consider integrating with EventBridge as an SaaS partner.

Conclusion

Event-driven architectures present a powerful opportunity for building scalable multi-account activity monitoring solutions. Using services such as AWS CloudTrail and Amazon EventBridge allows teams to overcome the limitations of traditional polling-based approaches while achieving close to real-time delivery.The shift to event-driven security monitoring isn’t just an architectural choice—it’s becoming a necessity for teams operating at enterprise scale. This approach enables security teams to achieve the real-time threat detection capabilities needed in today’s cloud environments while maintaining operational efficiency and cost control.

Optimizing fleet operations using Amazon SageMaker AI and Amazon Bedrock

Post Syndicated from Manny Sidhu original https://aws.amazon.com/blogs/architecture/optimizing-fleet-operations-using-amazon-sagemaker-ai-and-amazon-bedrock/

Every year in the United States, distracted driving claims thousands of lives and causes immense financial damage. More than 1.6 million accidents annually are caused by cell phone use while driving, and another 1.5 million result from drowsy drivers falling asleep at the wheel. These devastating—and preventable—accidents have sparked a major push for enhanced driver safety.

This initiative is particularly crucial in the commercial fleet industry, as accidents involving a large truck are often more dangerous and can cost hundreds of thousands of dollars. This post explores an innovative solution that leverages Amazon SageMaker AI and Amazon Bedrock to revolutionize driver coaching and enhance fleet efficiency. By harnessing the power of machine learning and artificial intelligence, we demonstrate how fleet operators can transform raw dashcam footage into actionable insights, empowering real-time driver monitoring and proactive safety measures – reducing costly accidents. Our approach combines AWS Artificial Intelligence (AI) and Internet of Things (IoT) services to create a comprehensive solution that not only detects distracted driving but also continuously improves its performance over time. Through this solution, we aim to show how fleet managers can significantly reduce distracted driving incidents, improve operational efficiency, and ultimately drive down costs in their commercial vehicle operations.

The Challenge: Effectively managing multiple dashcam feeds from commercial vehicle fleet

Today’s commercial vehicles are equipped with multi-camera systems that provide comprehensive coverage: inward-facing cameras monitor driver behavior, outward-facing cameras track oncoming traffic, and side/rear cameras detect cross-traffic and potential rear-end collisions. The sheer volume of video data generated by thousands of vehicles daily creates significant management and analysis challenges. While fleet operators traditionally use this dashcam footage for reactive purposes – such as law enforcement reporting, insurance claims, and driver exoneration – many organizations are missing a significant opportunity to leverage this data. As commercial fleets accumulate more miles, they generate rich datasets that can be used to train AI models capable of facilitating proactive safety improvements.

In this post, we’ll explore how to maximize the value of dashcam footage through best practices for implementing and managing Computer Vision systems in commercial fleet operations. We’ll demonstrate how to build and deploy edge-based machine learning models that provide real-time alerts for distracted driving behaviors, while effectively collecting, processing, and analyzing footage to train these AI models. This approach transforms fleet operations from reactive incident management to proactive safety enhancement, helping organizations convert raw video data into actionable insights that reduce safety incidents and improve overall fleet operational efficiency and cost-effectiveness.

Solution overview

A Distracted Driving Incident can occur when drivers engage in unsafe behaviors such as speeding, rolling stops, harsh braking, and aggressive acceleration. Fleet managers need to understand not just what happened during these incidents, but also the driver’s state of attention – whether they were focused on the road or distracted by activities like using a cellphone, eating, drinking, or experiencing fatigue common in long-haul driving.

Our solution leverages AWS services to create an end-to-end workflow capable of detecting and mitigating distracted driving. The steps involved include:

  1. Incident capture, ingestion, and labeling
  2. Model training, optimization, and deployment
  3. Continuous testing and improvement

Solution deep dive

This solution relies on a mix of AWS IoT, AI and generative AI services to build a scalable and cost-effective solution. Let’s start by looking at high level solution architecture and build the solution step-by-step.

Incident capture, ingestion, and labeling

To start the process of ingesting videos from a driver’s dashboard camera into the cloud, we capture the dashcam’s feed using the IoT Greengrass Kinesis Video Streamer Component. The video is streamed into the AWS Cloud using Kinesis Video Streams and stored in Amazon S3 by leveraging Kinesis Firehose. The videos are then converted into individual frames, analyzed by the Amazon Bedrock Nova Pro model to determine driver distraction, and sorted by an AWS Lambda function into an S3 bucket based on the analysis results. The sorted frames will next be used to train an AI model for edge deployment to detect distracted driving.

From a security perspective, it’s good practice to encrypt data in Amazon S3 buckets using AWS Key Management Service (KMS). You can enforce this by setting up SSE-KMS as the default encryption method to automatically encrypt uploaded objects. We also recommend implementing fine-grained AWS Identity & Access Management (IAM) roles to grant scoped access to images and videos. For data in transit between the edge and the cloud, you can use AWS IoT Greengrass certificates to encrypt your data and enforce identity verification. These measures can help protect against unauthorized access.

Edge-to-cloud architecture for real-time driver monitoring using AWS IoT, Kinesis, and ML services

With this process in place, we are continually collecting data from our fleet of commercial vehicles (while keeping security in mind). This data is automatically categorized and labeled based on the analysis from our Nova Pro model, and conveniently stored in S3, enabling us to seamlessly train an AI model – a process which we will describe next.

Model training, optimization, and deployment

The following diagram illustrates the process of training and deploying a distracted driver detection model. The process runs inside of an Amazon SageMaker Pipelines Workflow, which allows for seamless orchestration of other Amazon SageMaker AI services. This workflow begins with labeled driver images stored in Amazon S3, generated from the previously described workflow. This labeled dataset – consisting of driver images labeled as “distracted” or “not distracted’ – is used to train a ResNet50 model using Amazon SageMaker Training Jobs running on a Trn1 instance for price performance. As we train, the model learns how to identify distracted drivers. Once complete, the trained model is then quantized to INT8 using SageMaker Processing Jobs, and optimized for our specific type of edge hardware using SageMaker Neo. The optimized model is then stored in the SageMaker Model Registry for version control and governance (this will be helpful later when we iterate on our model with new training data). Finally, the model is pushed to S3 where AWS IoT Greengrass can initiate a deployment to the fleet of edge devices.

Running on the edge, the model performs inference multiple times a second on frames from the inward facing dashcam. (Inference speed calculated assuming edge compute has specs comparable to a Raspberry-Pi class of device.) If the driver is found to be distracted, the system alerts the driver by means of a noise. (ex. driver was falling asleep, and alert awakens them).

End-to-end AWS architecture for distracted driver detection: from model training to edge deployment

With this process in place, we have successfully leveraged the dataset we generated in the first diagram to train, optimize, and deploy our custom model to the ‘edge’ – in this case, to each vehicle in our fleet. Our model is now alerting drivers of dangerous behavior and helping to proactively prevent collisions. But our model likely isn’t perfect – perhaps it misses a dangerous behavior that wasn’t in the training dataset, or alerts unnecessarily. To validate our model is working well and further improve it to reduce errors, we implement continuous testing and improvement procedures.

Continuous testing and improvement

We need to continue to ingest driver dashcam data and compare our edge model’s predictions with our original source of ‘ground truth’ – Nova Pro.

The system collects frames for model validation in two scenarios: when vehicle telemetry detects incidents (hard braking, crashes) or when the edge model identifies distracted driving. These frames are sent to Amazon Bedrock for a ‘fact check’ to see if the edge model performed optimally. The comparative results between Amazon Bedrock and the edge model are stored in a dedicated S3 bucket for model evaluation. When sufficient new validated data is collected, or when the model’s agreement with Amazon Bedrock falls below a threshold, Amazon EventBridge triggers the previously described SageMaker Pipelines Workflow to fine tune, optimize, and re-deploy the improved model to the edge, now powered by our newly collected ‘disagreement data’.

Edge-to-cloud feedback loop for ML model validation using AWS IoT, Bedrock, and SageMaker services

We should also perform comparative analysis of our new model against our historical models stored in the Amazon SageMaker Model Registry to validate that our latest model actually performs better than historical models, verifying we don’t see a regression. If our latest model doesn’t outperform historical models, we should not deploy it, and instead investigate if we are suffering from overfitting or bad training data. In summary, we now have a model running inside fleet vehicles capable of alerting drivers to unsafe behavior. This could effectively reduce drowsy driving accidents by keeping drivers awake and alert, while also warning drivers about unsafe decisions like eating or using a cell phone while driving. This system is also self-training and self-improving, so it will continue to get better over time. Additionally, fleet management companies could aggregate safety data and reward top drivers to further incentivize safe driving habits.

Conclusion

In this post, we’ve explored an innovative solution that leverages AWS services to revolutionize driver coaching and fleet operations. By combining the power of Amazon SageMaker and Amazon Bedrock with AWS IoT and edge computing capabilities, we’ve demonstrated how to create a comprehensive, scalable solution for monitoring and improving driver behavior in real-time. This solution addresses the challenges of managing vast amounts of dashcam footage from commercial vehicle fleets, transforming raw video data into actionable insights. By implementing an end-to-end workflow that includes incident capture, categorization, model training, deployment, and continuous improvement, fleet operators can shift from reactive incident management to proactive safety enhancement. The benefits of this approach include:

  1. Enhanced safety: Real-time detection of distracted driving behaviors allows for immediate intervention and coaching.
  2. Improved efficiency: Automated analysis of dashcam footage reduces manual review time and costs.
  3. Scalability: The solution can handle large fleets and growing datasets with ease.
  4. Continuous improvement: The system learns and adapts over time, becoming more accurate and effective.
  5. Cost-effectiveness: By leveraging edge computing and optimized models, the solution minimizes compute costs.

As the transportation industry continues to evolve, solutions like this will play a crucial role in improving road safety, reducing operational costs, and enhancing overall fleet performance. By harnessing the power of AI and cloud computing, fleet operators can create safer, more efficient driving environments that benefit not only their businesses but also society as a whole. The future of fleet operations is here, and it’s driven by intelligent, data-driven systems that turn every mile driven into an opportunity for improvement and innovation.

Learn more by exploring AWS code samples to build hands-on SageMaker expertise. See the service in action through practical examples that demonstrate how to optimize model training and deployment across various use cases. Understand the financial advantages by conducting a cloud economics TCO analysis comparing traditional infrastructure against SageMaker’s managed services. This exercise reveals how SageMaker alleviates hidden costs while accelerating your ML development cycle.

Ready to take the next step? Connect with your AWS Solutions Architect to arrange a SageMaker AI Immersion Day tailored to your team’s specific challenges. These expert-led sessions provide personalized guidance that will help you implement SageMaker effectively within your organization’s unique context. For deeper dive into other relevant services Amazon Kinesis Video Streams, AWS IoT Greengrass, Amazon Bedrock


About the authors

[$] Glibc project revisits infrastructure security

Post Syndicated from jzb original https://lwn.net/Articles/1021837/

The GNU C Library
(glibc) is the core C library for most Linux distributions, so it is a
crucial part of the open-source ecosystem—and an attractive
target for any attackers looking to carry out supply-chain
attacks. With that being the case, securing the project’s
infrastructure using industry best practices and improving the
security of its development practices are a frequent topic among glibc
developers. A recent discussion suggests that improvements are not
happening as quickly as some would like.

Building a Conversational AI Chatbot Website with Backblaze B2 + LangChain

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/building-a-conversational-ai-chatbot-website-with-backblaze-b2-langchain/

A decorative image showing a cloud with the Backblaze logo with code imagery.

In an earlier blog post, I explained how to build your own LLM with Backblaze B2 + Jupyter Notebook, implementing a simple conversational AI chatbot using the LangChain AI framework to implement retrieval-augmented generation (RAG). The notebook walks you through the process of loading PDF files from a Backblaze B2 Bucket into a vector store, running a local instance of a large language model (LLM) and combining those to form a chatbot that can answer questions on its specialist subject.

That article generated a lot of interest, and a few questions:

  • “Could you make this into a web app, like ChatGPT?”
  • “Could you use this with OpenAI? DeepSeek?”
  • “Could I load multiple collections of documents into this?”
  • “Could I run multiple LLMs and compare them?”
  • “Can I add new documents to the vector store as they are uploaded to the bucket?”

The answer to all of these questions is “Yes!”

Today, I’ll present a simple conversational AI chatbot web app with a ChatGPT-style UI that you can easily configure to work with OpenAI, DeepSeek, or any of a range of other LLMs. In future blog posts, I’ll extend this to allow you to configure multiple LLMs and document collections, and integrate with Backblaze B2’s Event Notifications feature to load documents into the vector store within seconds of them being uploaded.

And, here’s a very short video of the chatbot in action:

Editorial note: A version of this article was previously published on the New Stack.

RAG basics

Retrieval-augmented generation, or RAG for short, is a technique that applies the generative features of an LLM to a collection of documents, resulting in a chatbot that can effectively answer questions based on the content of those documents.

A typical RAG implementation splits each document in the collection into a number of roughly equal-sized, overlapping chunks, and generates an embedding for each chunk. Embeddings are vectors (lists) of floating point numbers with hundreds or thousands of dimensions. The distance between two vectors indicates their similarity. Small distances indicate high similarity and large distances indicate low similarity.

The RAG app then loads each chunk, along with its embedding, into a vector store. The vector store is a special-purpose database that can perform a similarity search–given a piece of text, the vector store can retrieve chunks ranked by their similarity to the query text by comparing the embeddings.

Let’s put the pieces together:

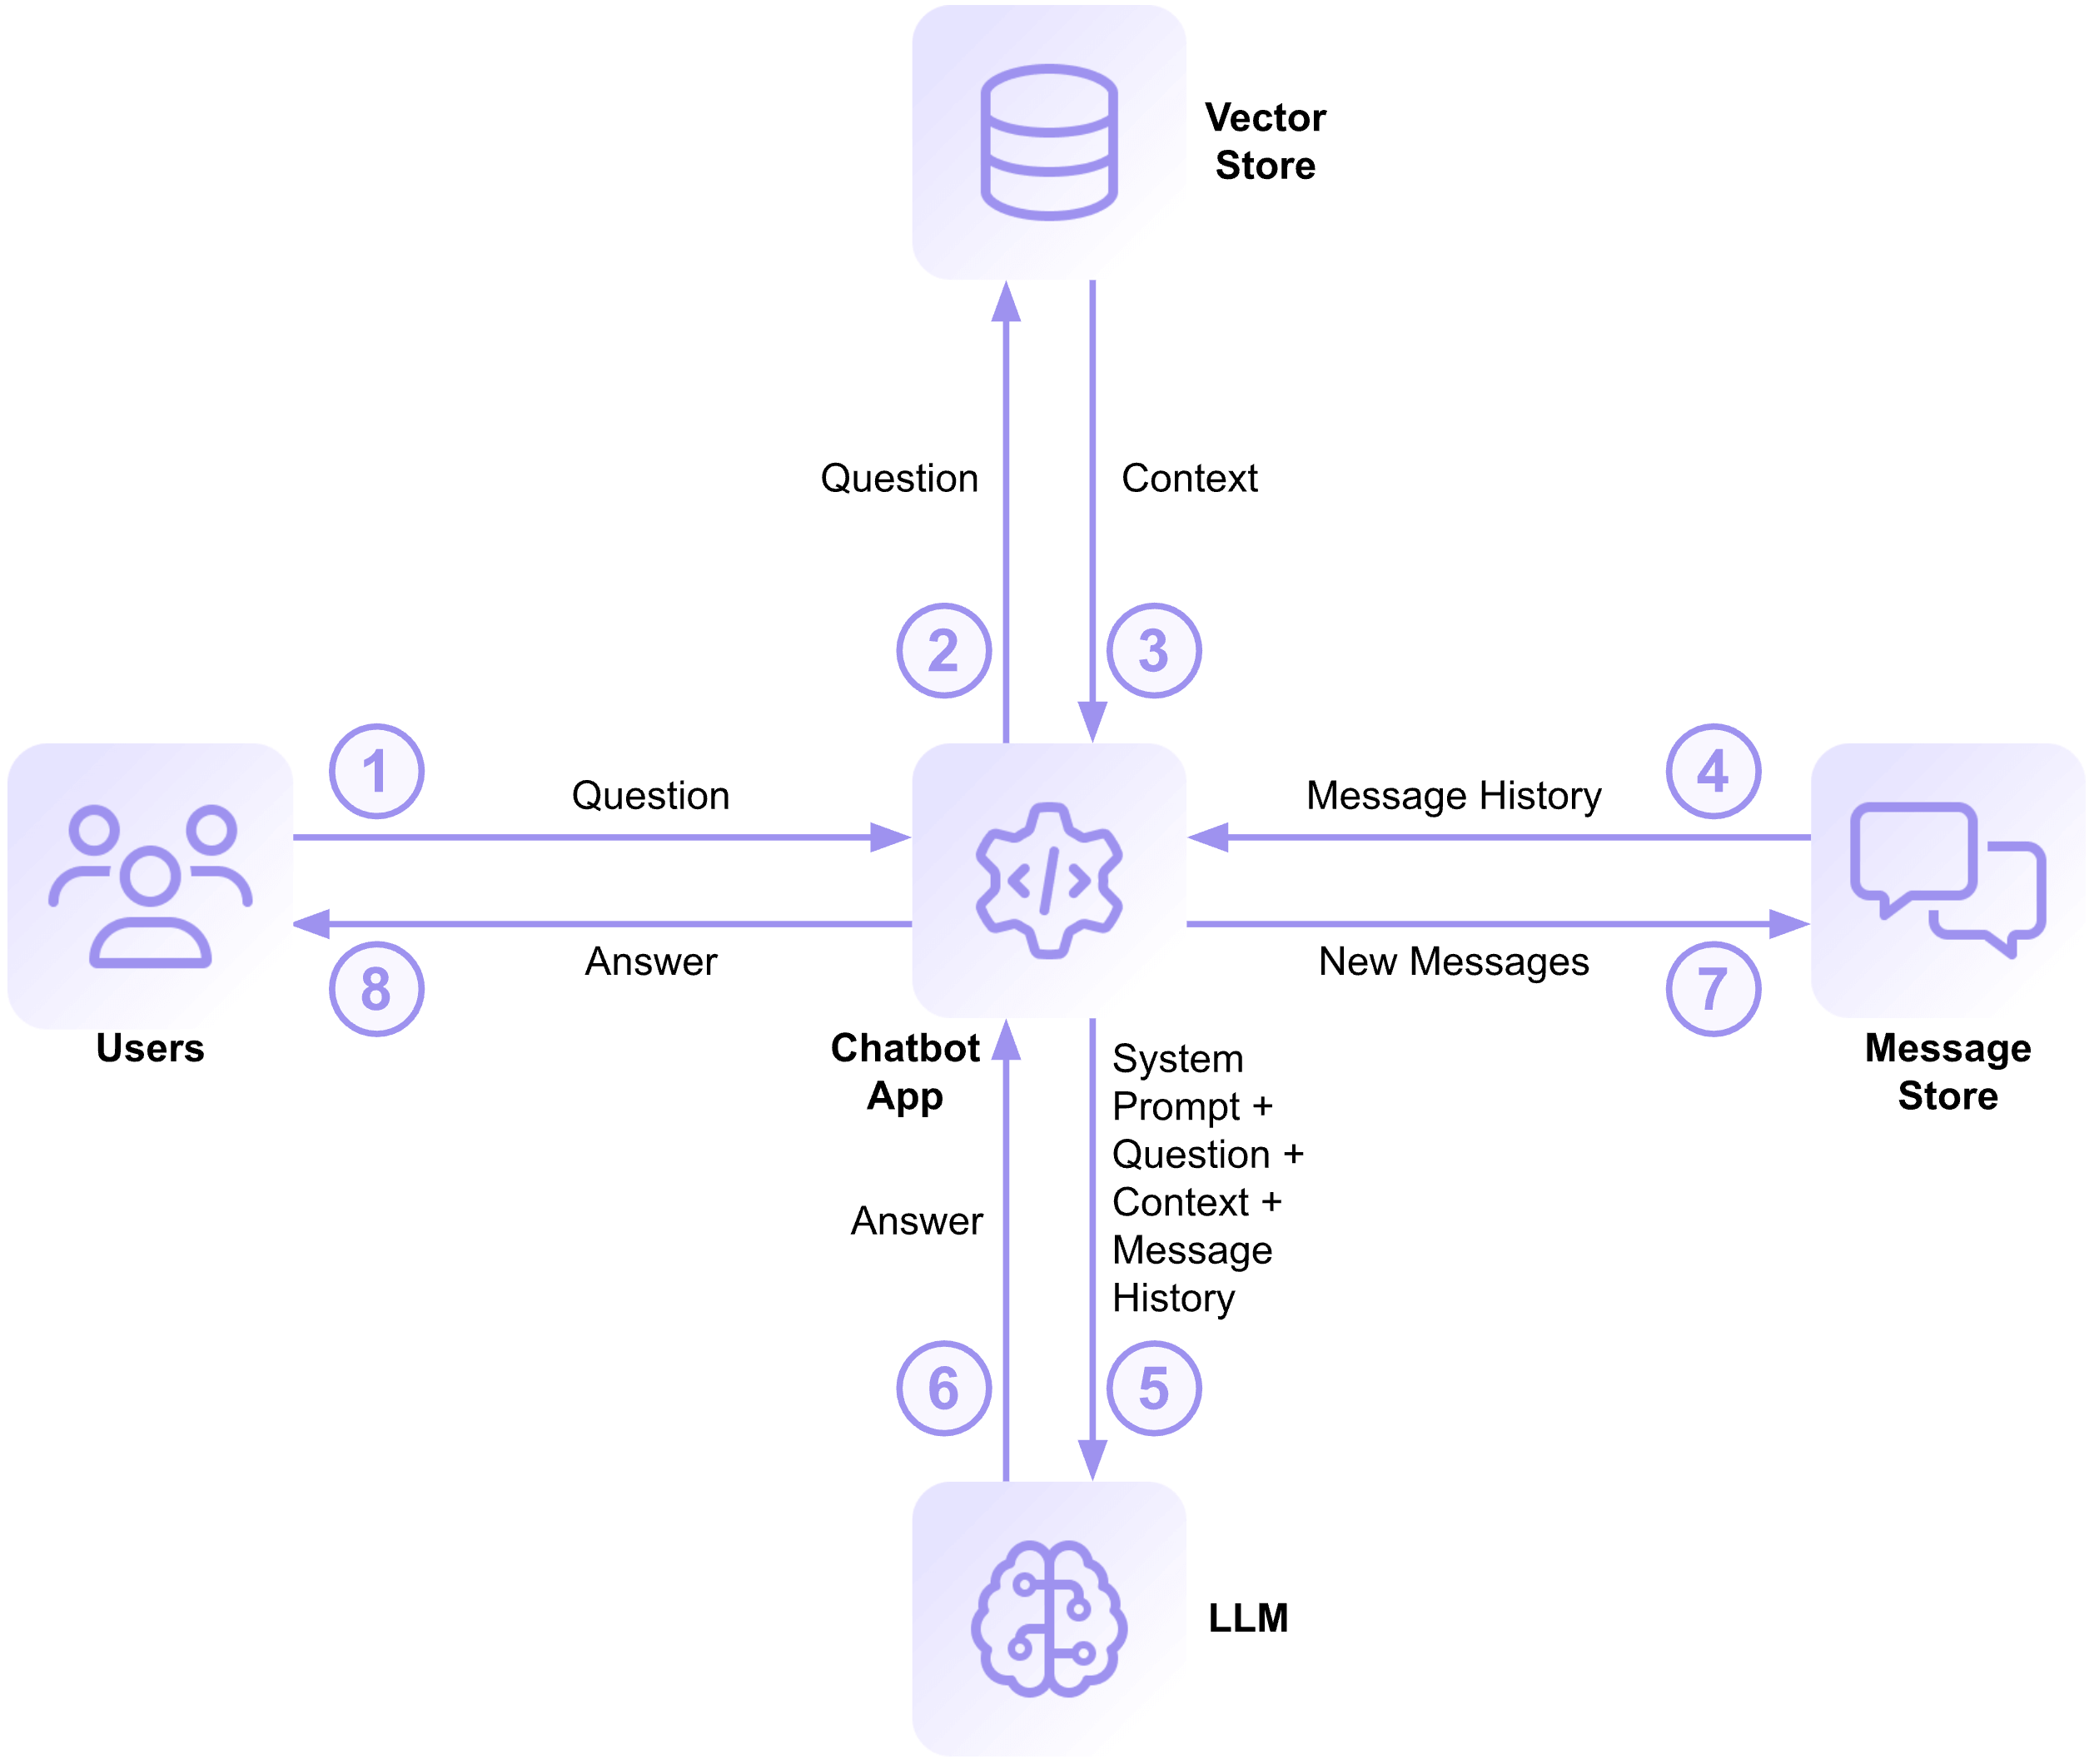
Given a question from the user (1), the RAG app can query the vector store for chunks of text that are similar to the question (2). This will be the context that helps the LLM answer the user’s question. Here’s a concrete example using the Backblaze documentation collection: Given the question, “Tell me about object lock,” the vector store returns four document chunks, each of about 170 words, to the app (3). Here is a link to the text of, and a short extract from, each chunk:

  • Object Lock: With Object Lock Legal Hold, files are prevented from being changed or deleted, but the immutability does not have a defined retention period.
  • Object Lock: You can enable Object Lock on a bucket when you create a new bucket or on an existing bucket.
  • Object Lock: Object Lock in Backblaze B2 was designed with the Immutability feature in Veeam Backup & Replication in mind.
  • Enable Object Lock with the S3 Compatible API: To enable Object Lock on an existing S3 compatible bucket, add the x-amz-bucket-object-lock-token header with a value of 1 to the S3 Put Object Lock Configuration API call.

Unsurprisingly, three of the four results are extracts from the main documentation article on Object Lock.

In order to provide a conversational experience, the RAG app maintains a chat history in a message store. The RAG app retrieves the message history (4) to form part of the query it will send to the LLM.

A system prompt sets the guidelines for the LLM to generate responses. In a RAG, the system prompt typically specifies that the response should be based on retrieved document data rather than model memorization, and attempts to prevent hallucinations by ensuring that the model does not fabricate information if no relevant documents are found. Here is the system prompt from the RAG app:

Use the following pieces of context and the message history to answer the question at the end. If you don't know the answer,  just say that you don't know, don't try to make up an answer.

The RAG submits the system prompt, the context, the last few messages in the conversation, and the user’s question to the LLM (5), which generates a, hopefully useful, response (6). Here’s the answer it provided to the above question:

Object Lock is a feature that allows users to enforce immutability on files stored in cloud storage, specifically in services like Backblaze B2 and AWS S3. Here are the key points about Object Lock:

  1. Immutability: Once a file is locked, it cannot be modified or deleted until a specified retention period expires or a legal hold is lifted.
  2. Retention Periods: Users can set a retention period when locking a file. During this time, the file remains immutable, meaning it cannot be changed or deleted.
  3. Legal Hold: Users can place files under a legal hold, which prevents modifications or deletions indefinitely until the hold is removed.
  4. Enabling Object Lock: Object Lock can be enabled for new buckets or existing ones, but it must be turned on at the bucket level before files are uploaded.
  5. Integrations: Some applications, like Veeam Backup & Replication, offer built-in support for Object Lock, making the process easier for users when they want to ensure file immutability during backups.
  6. No Extra Cost: There is no additional fee for using Object Lock; however, standard storage charges for the locked files still apply.
  7. Mistakes in Locking: If a user locks a file for longer than intended, they may need to contact support to resolve the situation, which could involve closing their storage account in some cases.

Overall, Object Lock is a crucial feature for organizations that need to ensure data integrity and compliance with regulations concerning data retention.

The RAG app adds the user’s question and the LLM’s response to the message store (7), returns the answer to the user (8), and awaits the next question.

A quick tour of the sample app

The sample app is on GitHub at https://github.com/backblaze-b2-samples/ai-rag-app. The app is open source, under the MIT license, so you can use it as a basis for your own experimentation without any restrictions. The app was originally written to demonstrate RAG with Backblaze B2 Cloud Storage, but it works with any S3 compatible object store.  

The README file covers configuration and deployment in some detail; in this blog post, I’ll just give you a high-level overview. The sample app is written in Python using the Django web framework. API credentials and related settings are configured via environment variables, while the LLM and vector store are configured via Django’s settings.py file:

CHAT_MODEL: ModelSpec = {
'name': 'OpenAI',
'llm': {
'cls': ChatOpenAI,
'init_args': {
'model': "gpt-4o-mini",
}
},
}

# Change source_data_location and vector_store_location to match your environment
# search_k is the number of results to return when searching the vector store
DOCUMENT_COLLECTION: CollectionSpec = {
'name': 'Docs',
'source_data_location': 's3://blze-ev-ai-rag-app/pdfs',
'vector_store_location': 's3://blze-ev-ai-rag-app/vectordb/docs/openai',
'search_k': 4,
'embeddings': {
'cls': OpenAIEmbeddings,
'init_args': {
'model': "text-embedding-3-large",
},
},
}

The sample app is configured to use OpenAI GPT-4o mini, but the README explains how to use different online LLMs such as DeepSeek V3 or Google Gemini 2.0 Flash, or even a local LLM such as Meta Llama 3.1 via the Ollama framework. If you do run a local LLM, be sure to pick a model that fits your hardware. I tried running Meta’s Llama 3.3, which has 70 billion parameters (70B), on my MacBook Pro with the M1 Pro CPU. It took nearly three hours to answer a single question! Llama 3.1 8B was a much better fit, answering questions in less than 30 seconds.

Notice that the document collection is configured with the location of a vector store containing the Backblaze documentation as a sample dataset. The README file contains an application key with read-only access to the PDFs and vector store so you can try the application without having to load your own set of documents.

If you want to use your own document collection, a pair of custom commands allow you to load them from a Backblaze B2 Bucket into the vector store and then query the vector store to test that it all worked.

First, you need to load your data:

% python manage.py load_vector_store
Deleting existing LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs
Creating LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs
Loading data from s3://blze-ev-ai-rag-app/pdfs in pages of 1000 results
Successfully retrieved page 1 containing 618 result(s) from s3://blze-ev-ai-rag-app/pdfs
Skipping pdfs/.bzEmpty
Skipping pdfs/cloud_storage/.bzEmpty
Loading pdfs/cloud_storage/cloud-storage-about-backblaze-b2-cloud-storage.pdf
Loading pdfs/cloud_storage/cloud-storage-add-file-information-with-the-native-api.pdf
Loading pdfs/cloud_storage/cloud-storage-additional-resources.pdf
...
Loading pdfs/v1_api/s3-put-object.pdf
Loading pdfs/v1_api/s3-upload-part-copy.pdf
Loading pdfs/v1_api/s3-upload-part.pdf
Loaded batch of 614 document(s) from page
Split batch into 2758 chunks
[2025-02-28T01:26:11Z WARN lance_table::io::commit] Using unsafe commit handler. Concurrent writes may result in data loss. Consider providing a commit handler that prevents conflicting writes.
Added chunks to vector store
Added 614 document(s) containing 2758 chunks to vector store; skipped 4 result(s).
Created LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs. "vectorstore" table contains 2758 rows

Now you can verify that the data is stored by querying the vector store. Notice how the raw results from the vector store include an S3 URI identifying the source document:

% python manage.py search_vector_store 'Which B2 native APIs would I use to upload large files?' 
2025-03-01 02:38:07,740 ai_rag_app.management.commands.search INFO Opening vector store at s3://blze-ev-ai-rag-app/vectordb/docs/openai
2025-03-01 02:38:07,740 ai_rag_app.utils.vectorstore DEBUG Populating AWS environment variables from the b2 profile
Found 4 docs in 2.30 seconds
2025-03-01 02:38:11,074 ai_rag_app.management.commands.search INFO
page_content='Parts of a large file can be uploaded and copied in parallel, which can significantly reduce the time it takes to upload terabytes of data. Each part can be anywhere from 5 MB to 5 GB, and you can pick the size that is most convenient for your application. For best upload performance, Backblaze recommends that you use the recommendedPartSize parameter that is returned by the b2_authorize_account operation. To upload larger files and data sets, you can use the command-line interface (CLI), the Native API, or an integration, such as Cyberduck. Usage for Large Files Generally, large files are treated the same as small files. The costs for the API calls are the same. You are charged for storage for the parts that you uploaded or copied. Usage is counted from the time the part is stored. When you call the b2_finish_large_file' metadata={'source': 's3://blze-ev-ai-rag-app/pdfs/cloud_storage/cloud-storage-large-files.pdf'}
...

The core of the sample application is the RAG class. There are several methods that create the basic components of the RAG, but here we’ll look at how the _create_chain() method brings together the system prompt, vector store, message history, and LLM.

First, we define the system prompt, which includes a placeholder for the context—those chunks of text that the RAG will retrieve from the vector store:

# These are the basic instructions for the LLM
system_prompt = (
"Use the following pieces of context and the message history to "
"answer the question at the end. If you don't know the answer, "
"just say that you don't know, don't try to make up an answer. "
"\n\n"
"Context: {context}"
)

Then we create a prompt template that brings together the system prompt, message history, and the user’s question:

# The prompt template brings together the system prompt, context, message history and the user's question
prompt_template = ChatPromptTemplate(
[
("system", system_prompt),
MessagesPlaceholder(variable_name="history", optional=True, n_messages=10),
("human", "{question}"),
]
)

Now we use LangChain Expression Language (LCEL) to bring the various components together to form a chain. LCEL allows us to define a chain of components declaratively; that is, we provide a high-level representation of the chain we want, rather than specifying how the components should fit together. 

Notice the log_data() helper method—it simply logs its input and passes it on to the next component in the chain.

# Create the basic chain
# When loglevel is set to DEBUG, log_input will log the results from the vector store
chain = (
{
"context": (
itemgetter("question")
| retriever
| log_data('Documents from vector store', pretty=True)
),
"question": itemgetter("question"),
"history": itemgetter("history"),
}
| prompt_template
| model
| log_data('Output from model', pretty=True)
)

Assigning a name to the chain allows us to add instrumentation when we invoke it:

# Give the chain a name so the handler can see it
named_chain: Runnable[Input, Output] = chain.with_config(run_name="my_chain")

Now, we use LangChain’s RunnableWithMessageHistory class to manage adding and retrieving messages from the message store:

# Add message history management
return RunnableWithMessageHistory(
named_chain,
lambda session_id: RAG._get_session_history(store, session_id),
input_messages_key="question",
history_messages_key="history",
)

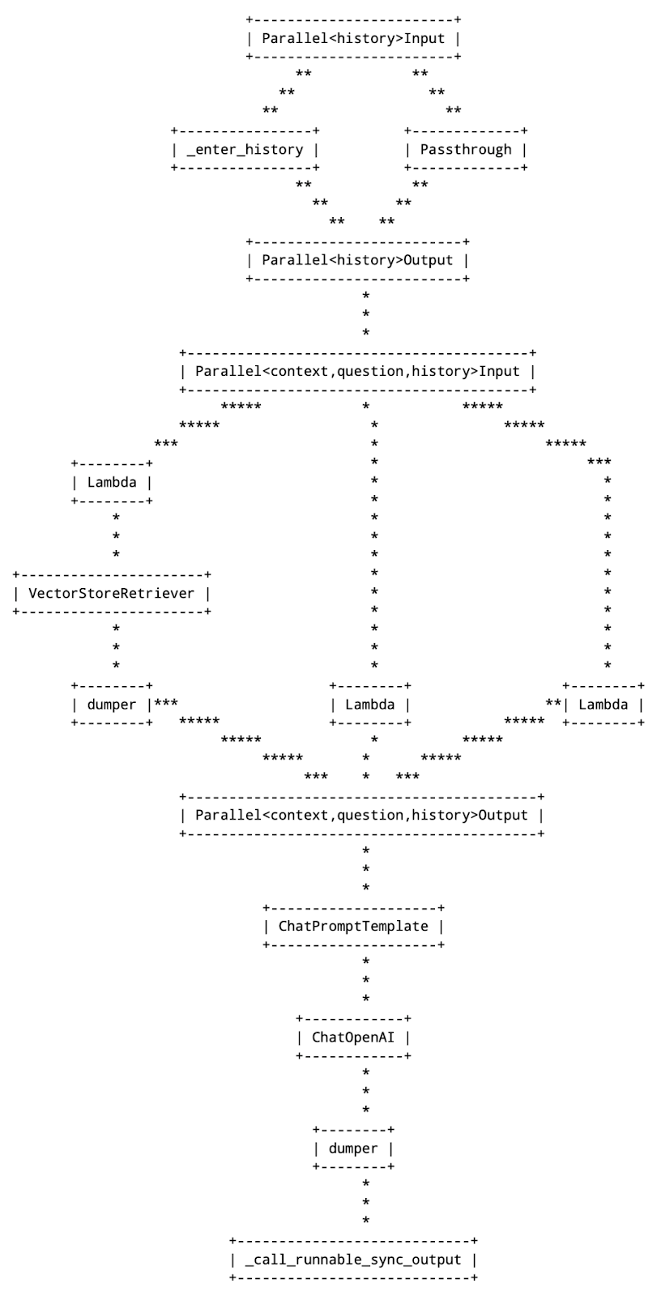
Finally, the log_chain() function prints an ASCII representation of the chain to the debug log:

log_chain(history_chain, logging.DEBUG, {"configurable": {'session_id': 'dummy'}})

This is the output:

The RAG class’ invoke() function, in contrast, is very simple. Here is the key section of code:

response = self._chain.invoke(
{"question": question},
config={
"configurable": {
"session_id": session_key
},
"callbacks": [
ChainElapsedTime("my_chain")
]
},
)

The input to the chain is a Python dictionary containing the question, while the config argument configures the chain with the Django session key and a callback that annotates the chain output with its execution time. Since the chain output contains Markdown formatting, the API endpoint that handles requests from the front end uses the open source markdown-it library to render the output to HTML for display.

The remainder of the code is mostly concerned with rendering the web UI. One interesting facet is that the Django view, responsible for rendering the UI as the page loads, uses the RAG’s message store to render the conversation, so if you reload the page, you don’t lose your context.

Take this code and run it!

The sample AI RAG application is open source under the MIT license, and I encourage you to use it as the basis for your own RAG exploration. The README file suggests a few ways you could extend it, and I also draw your attention to conclusion of the README if you are thinking of running the app in production:

[…] in order to get you started quickly, we streamlined the application in several ways. There are a few areas to attend to if you wish to run this app in a production setting:

Above all, have fun! AI is a rapidly evolving technology, with vendors and open source projects releasing new capabilities every day. I hope you find this app a useful way of jumping in.

The post Building a Conversational AI Chatbot Website with Backblaze B2 + LangChain appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Завръщането на буржоазния зеленчук

Post Syndicated from Чило Попов original https://www.toest.bg/zavrushtaneto-na-burzhoazniya-zelenchuk/

Завръщането на буржоазния зеленчук

Един виц за Катуница обяснява произхода на името ѝ с рицар кръстоносец, озовал се там по пътя си към Йерусалим. Като видял селото, възкликнал на чист български: „Кату Ница!“

Днес това наистина подредено, чисто и живо село е действително (а не като във виц) по-близо до Европа благодарение на едни будни и предприемчиви земеделци, които от около десет години насам с постоянство възстановяват отглеждането на някога традиционния за България зеленчук – аспержите. 

Малко история

Аспержите са отглеждани в продължение на десетилетия в Централна и Южна Тракия и по поречието на река Марица в периода от създаването на младата българска държава до 1945 г. Разказва се, че те, както и други култури, са донесени в България от агрономи от Чехия, които са си сътрудничили със земеделската опитна станция в град Садово, в чиято община се намира и село Катуница. Тук ще вмъкна и любопитния факт, че според една от версиите картофите, които са неизменна част от българската кулинарна традиция, са донесени в България от чешки минни инженери, които са разработвали рудници в Родопите около 1830 г. 

Завръщането на буржоазния зеленчук
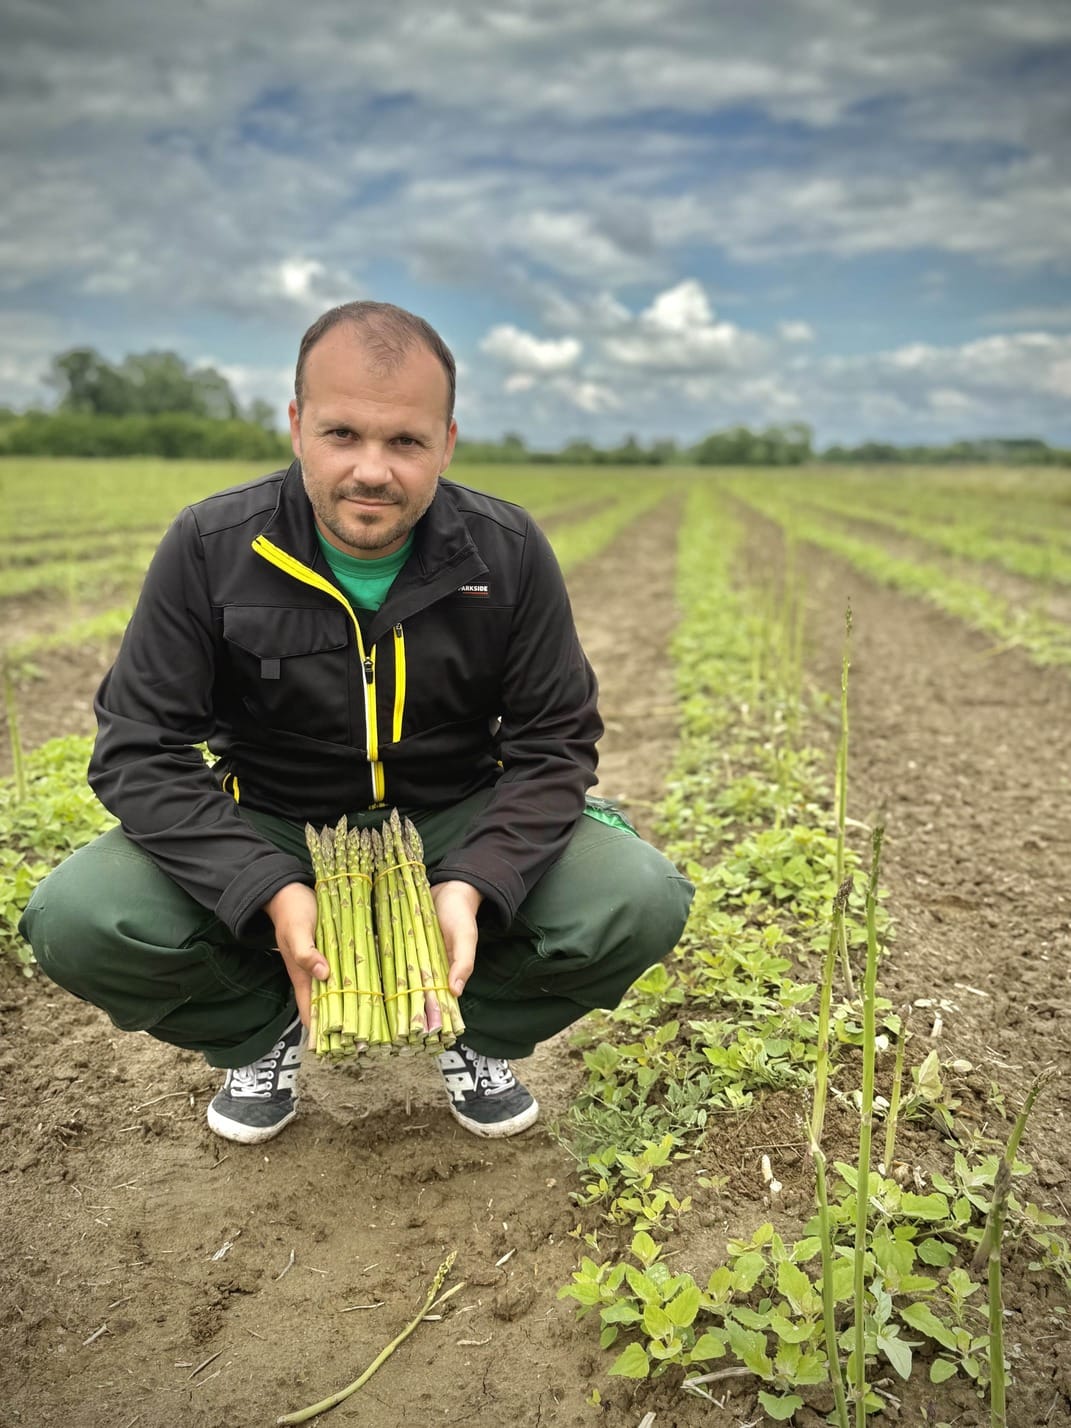
Виктор Илиев. Снимка: © Чило Попов

Заради потенциала на плодородната почва в Тракия започва засаждането на все повече аспержи. За кратко време то така се разраства, че България се превръща в значим износител за Западна Европа на аспержи и ягоди, които малко по-рано идват по тракийските земи, също донесени от чехите. 

За жалост на производители и ценители, след 1945 г. комунистическият режим обявява аспержите за „бyржоазен“ зеленчук и проводник на упадъчна култура и нарежда унищожаването на всички насаждения в цялата страна. Десетилетията на тоталитарен мрак водят до изкореняването на зеленчука и от кулинарната традиция, и от спомените на хората, така че след краха на комунизма трябва да минат почти две десетилетия, докато потребители, търговци и производители се сетят, че аспержите някога са имали своето място в градините и кухните ни и е време това пак да бъде така.

Етимология и произход

Латинското име на растението е Asparagus officinalis и е директна заемка от старогръцки – ἀσπάραγος, което може да означава ‘гръклян’, но и ‘млада издънка’.

Както червеното цвекло се използва за оцветител, а синапът като афродизиак, така и аспержите първоначално са служили не за храна, а за лекарство. Произлизат от Западна Азия, където са били диворастящи. Древните гърци са използвали зеленчука като диуретик и прочистваща билка. Чак римляните започват да го култивират и той се превръща от лекарство в модерен зеленчук за заможните. Беден е на калории, но богат на фибри, витамин Е и В, фосфор, магнезий, калий и желязо. 

Както много други неща, древните гърци и римляните са смятали аспержите за афродизиак. Засега не е доказано. Заради това схващане обаче в Римската империя са били забранени за консумация от жените. В Древна Гърция жените пък са го използвали за амулет, предпазващ от зачеване. 

Турската дума за аспержа описва характерната форма на зеленчука особено цветущо: kuşkonmaz означава ‘където не може да кацне птица’. 

Завръщането на буржоазния зеленчук
Снимка: © Чило Попов

„Българско аспержи“*

Преди около шест години случайно разбрах за Виктор Илиев, който от 2001-ва е избрал градинарството за свое призвание. Заедно с баща си, подкрепящ го с опит и любов, създава първото аспержово насаждение в региона, в който още от 1902 г. са се отглеждали първите аспержи в България. Всяка година със семейството ми не пропускаме да се възползваме от този зеленчук в сравнително краткия му сезон, в чийто край се намираме, докато пиша тази статия. Ако се чудите кога аспержите са най-хубави – от края на март до края на май. През тези два месеца ние и гостите ни преяждаме с аспержите на Виктор и тъй като за мен е особена радост да отида лично да Катуница, за да си ги взема, не пропускам всеки път да си побъбря с този човек, бликащ от идеи и енергия и зареждащ околните с оптимизъм.

Рецепти за облагородени буржоа

За онагледяване на твърденията и за поощряване на консумацията, така че и читателите ни да се почувстват облагородени буржоа, споделям три рецепти с аспержи от моя профил в Instagram –
tchilo_garum.

Зелените аспержи са най-разпространените в България и се приготвят бързо и лесно. Те нямат нужда от дълга термична обработка и са изключително полезни и здравословни.

Почистват се като се чупят на ръка в дебелия им край – стъблото се държи с двете ръце близо до долния му край и при огъване „свещта“ се чупи там, където се разделят твърдата и крехката част. Белят се с 90-градусова белачка до средата на стъблото.

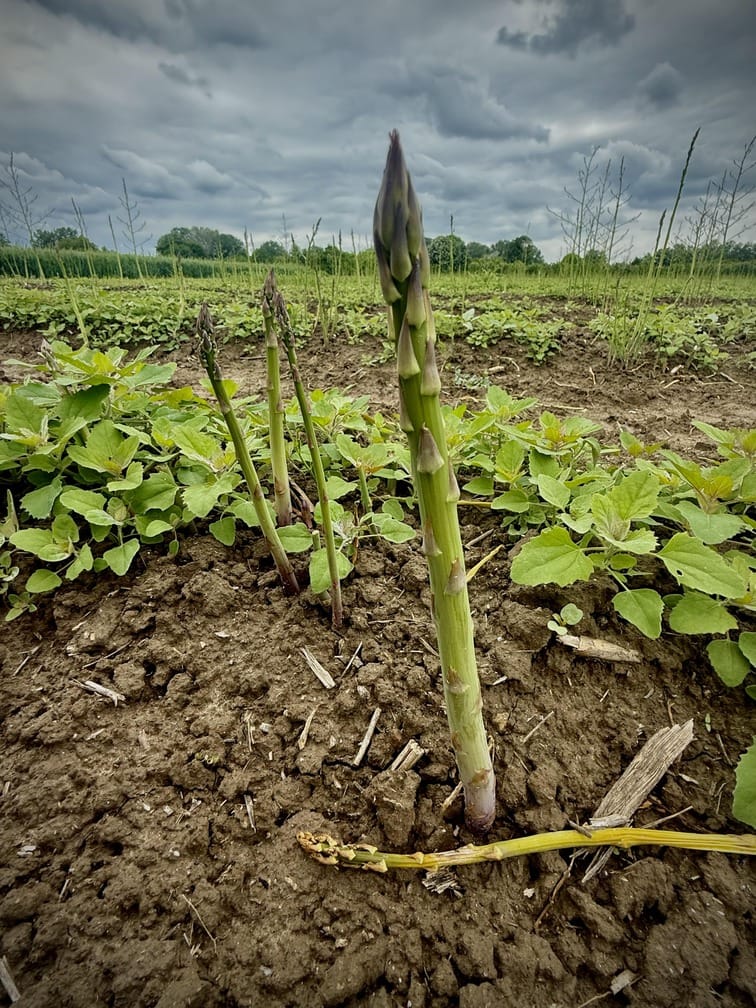
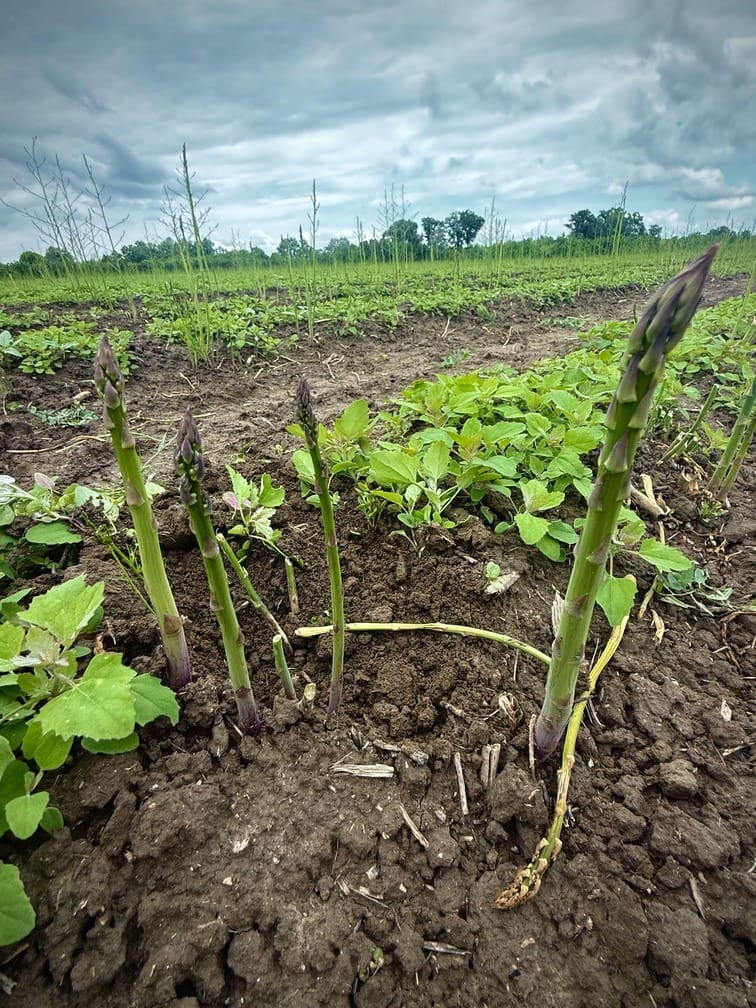
Наскоро, прибирайки поредната поръчка за мен и приятели, помолих Виктор да отидем до нивата, която, наред с още други земи, е семейна собственост от времето на прадядо му и където аспержовата територия се разраства всяка година. Към края на сезона „свещите“, както Виктор нарича надземната част на растението, са по-нарядко и са по-тънки, а честотата на брането е разредена. Тоест май хванах последния влак тази година, за да видя на живо плода на труда му.

Човек, решил се да гледа аспержи, трябва да е наясно, че освен краткия им сезон, има още няколко особености, които не са непременно аргументи в полза на аспержовите насаждения. 

Първото и най-интересно е, че след полагането на разсада в земята той носи реколта чак след третата година. Тогава аспержите развиват стабилно коренище, което всяка година изкарва много отделни филизи и свещи. При излизането си над повърхността позеленяват, а ако се загърлят в лехи и останат под пръстта, са си бели. Това е и разликата между белите и зелените аспержи.

Друга особеност е краткият сезон, който ограничава силно възможността за земеделците да използват оптимално площите си, тъй като аспержите са многогодишни растения с жизнен цикъл от около 20–25 години и това не позволява извън сезона на техните територии да се садят и отглеждат други култури.


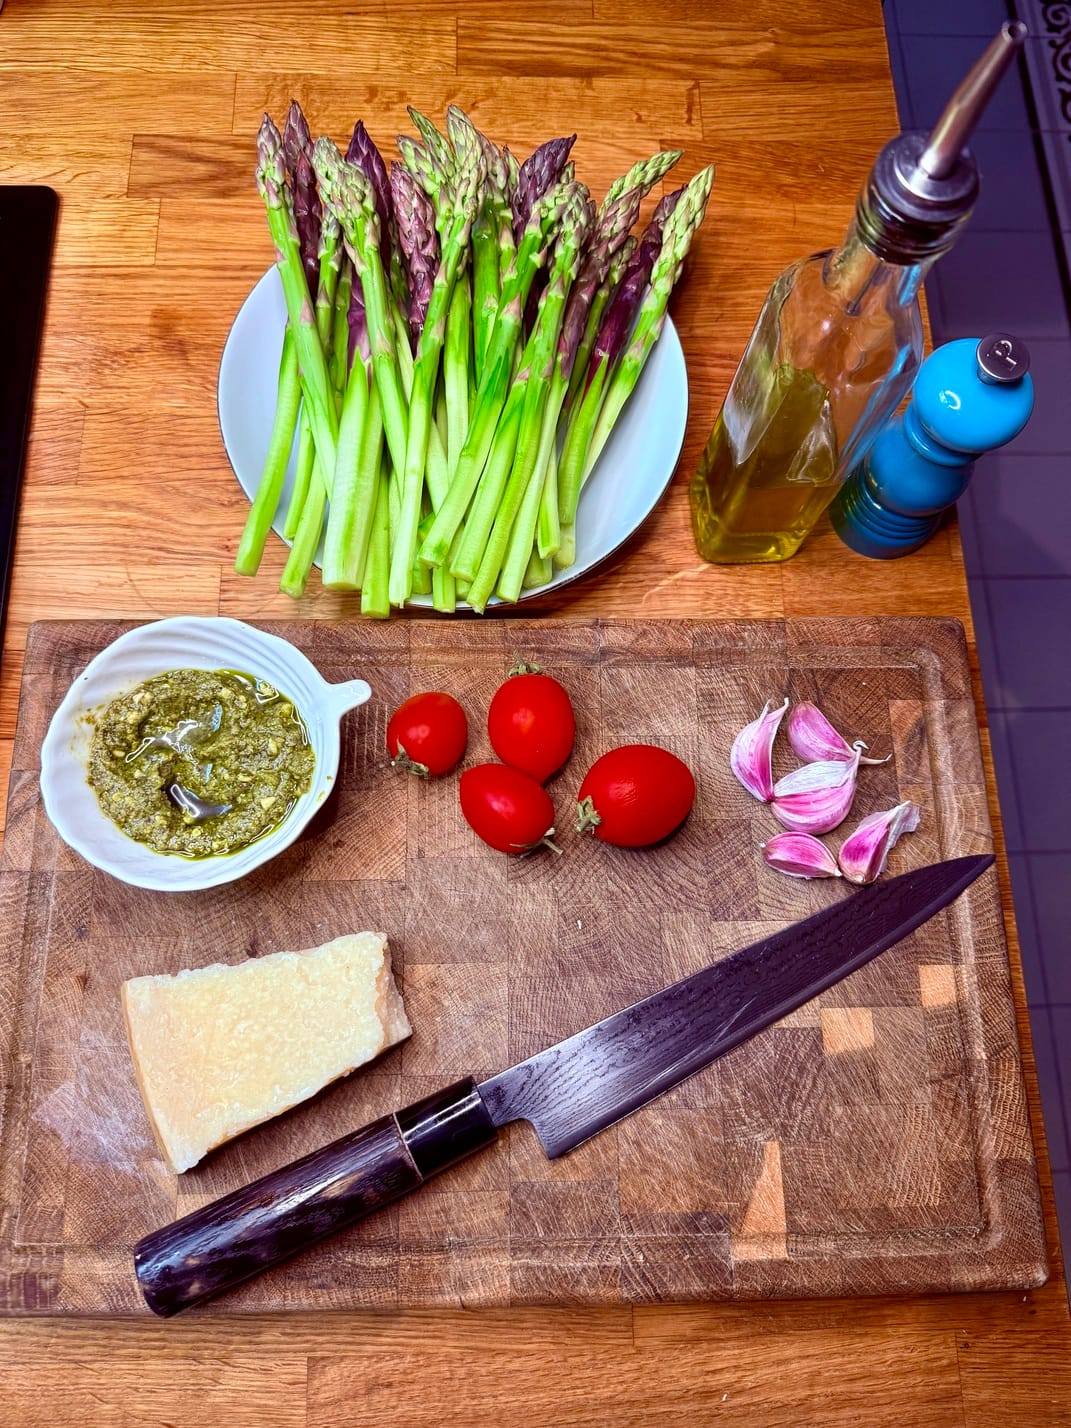
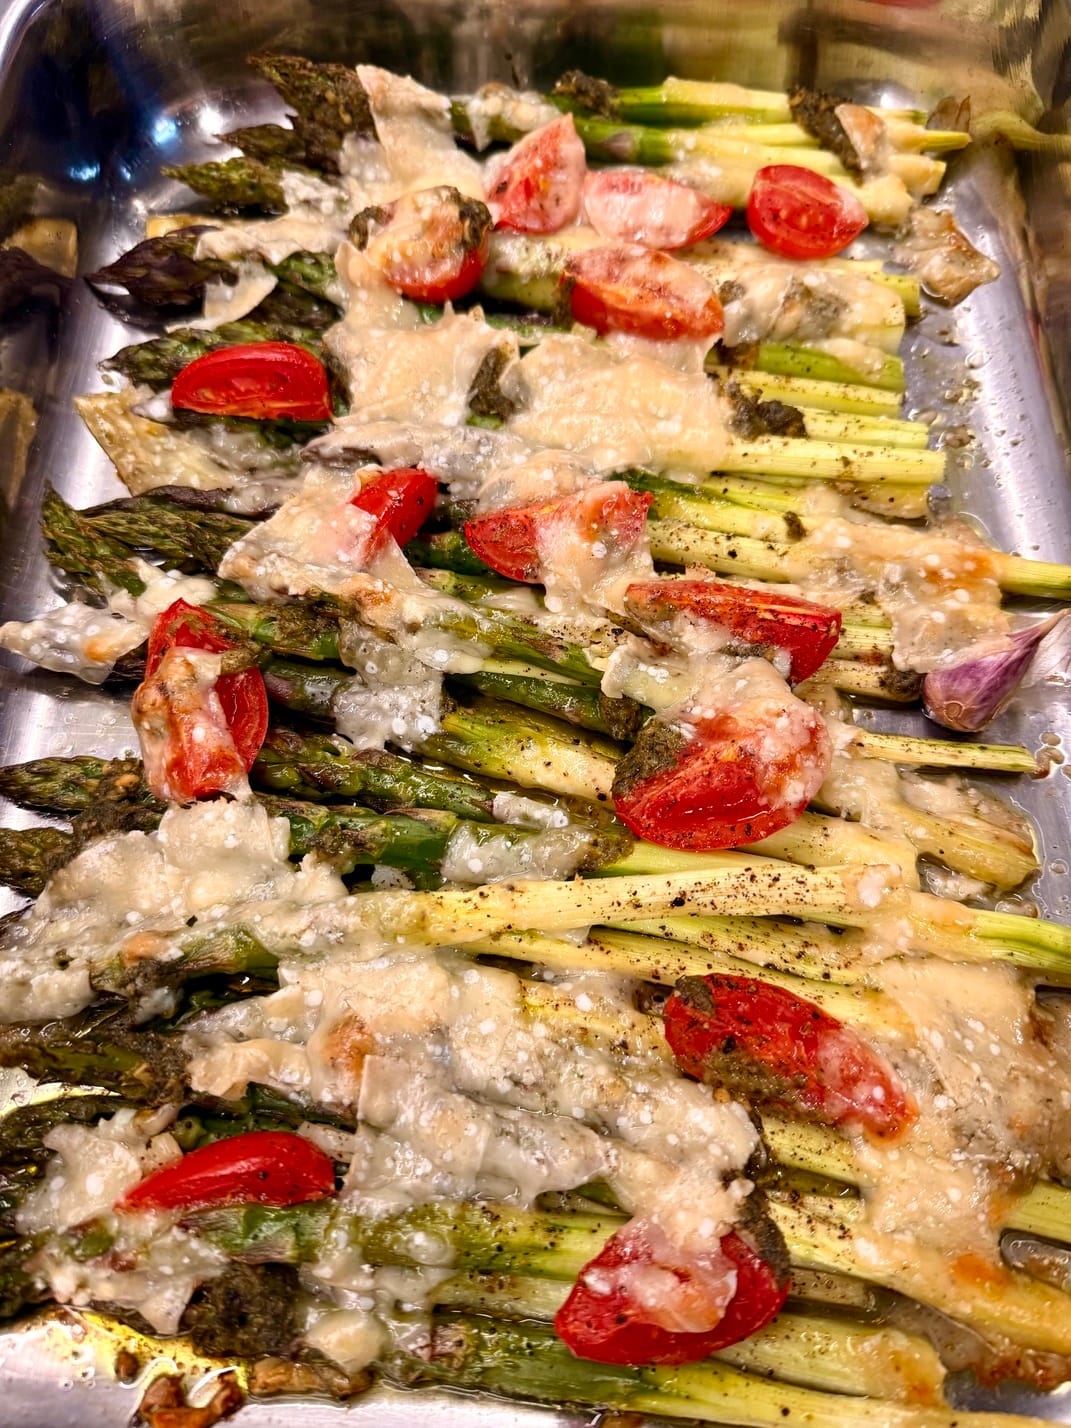
Зелени аспержи с пармезан, домати и песто на фурна


Почистените аспержи се нареждат в тава, намасляват се със зехтин и към тях се добавят няколко скилидки ситно нарязан чесън.

Аспержите с чесъна се посоляват и се поръсват щедро с люспи от пармезан (или друго твърдо сирене), две супени лъжици песто дженовезе, разпределени по повърхността, и две шепи разполовени чери доматчета.

Пекат се на 180°С за 15 минути в предварително загрята фурна.

През останалата част от годината 

Виктор отглежда около 6 дка пловдивска капия – една от най-вкусните чушки, има градина с тикви, а също и с дюли и мушмули. Интересно ми беше да разбера, че мушмулите много се търсят от търговците и той успява да продаде предварително почти цялата си реколта.

Спокойно и оптимистично се почувствах, когато стоях и гледах нивите на Виктор до коритото на река Чая, подредени и поддържани, и самия него – неспиращ да разказва истории, да крои планове за следващата година, когато очаква и първата реколта от новите лилави аспержи, доставени от Англия.

Връщаме се в семейната им къща в селото, в чиято градина се отглежда разсадът за цялото стопанство, поддържа се техниката и се мият и подреждат „свещите“ на специална поточна минилиния за миене и сортиране, закупена на старо от Германия и върната към живот в село Катуница. 

Завръщането на буржоазния зеленчук
Снимка: © Чило Попов

Всичко е скромно и честно, затова буди и такива симпатии у мен като посетител, а вече и като приятел. Тракторът „Болгар“ се поддържа и ремонтира добре и затова още служи вярно, фрезата е от Вазовските заводи, а плугът – от ГДР. Виктор отдавна се е отказал да разчита за каквото и да е на държавата. Твърди, че е по-добре да си свърши сам работата и да се разпростира и планира според чергата си, вместо да инвестира време и енергия в попълване на безкрайни формуляри и подготовка на десетки документи, които биха го наредили сред аутсайдерите за получаване на държавна помощ или субсидия, защото се занимава с градинарство, а не отглежда технически или монокултури в индустриални количества. И най-вече защото не е човек на някого и не се ползва с протекции.


Испански тиган с аспержи и скариди


Връзка и половина изчистени аспержи се нарязват диагонално на парчета от 3–4 см и се запържват в зехтин.

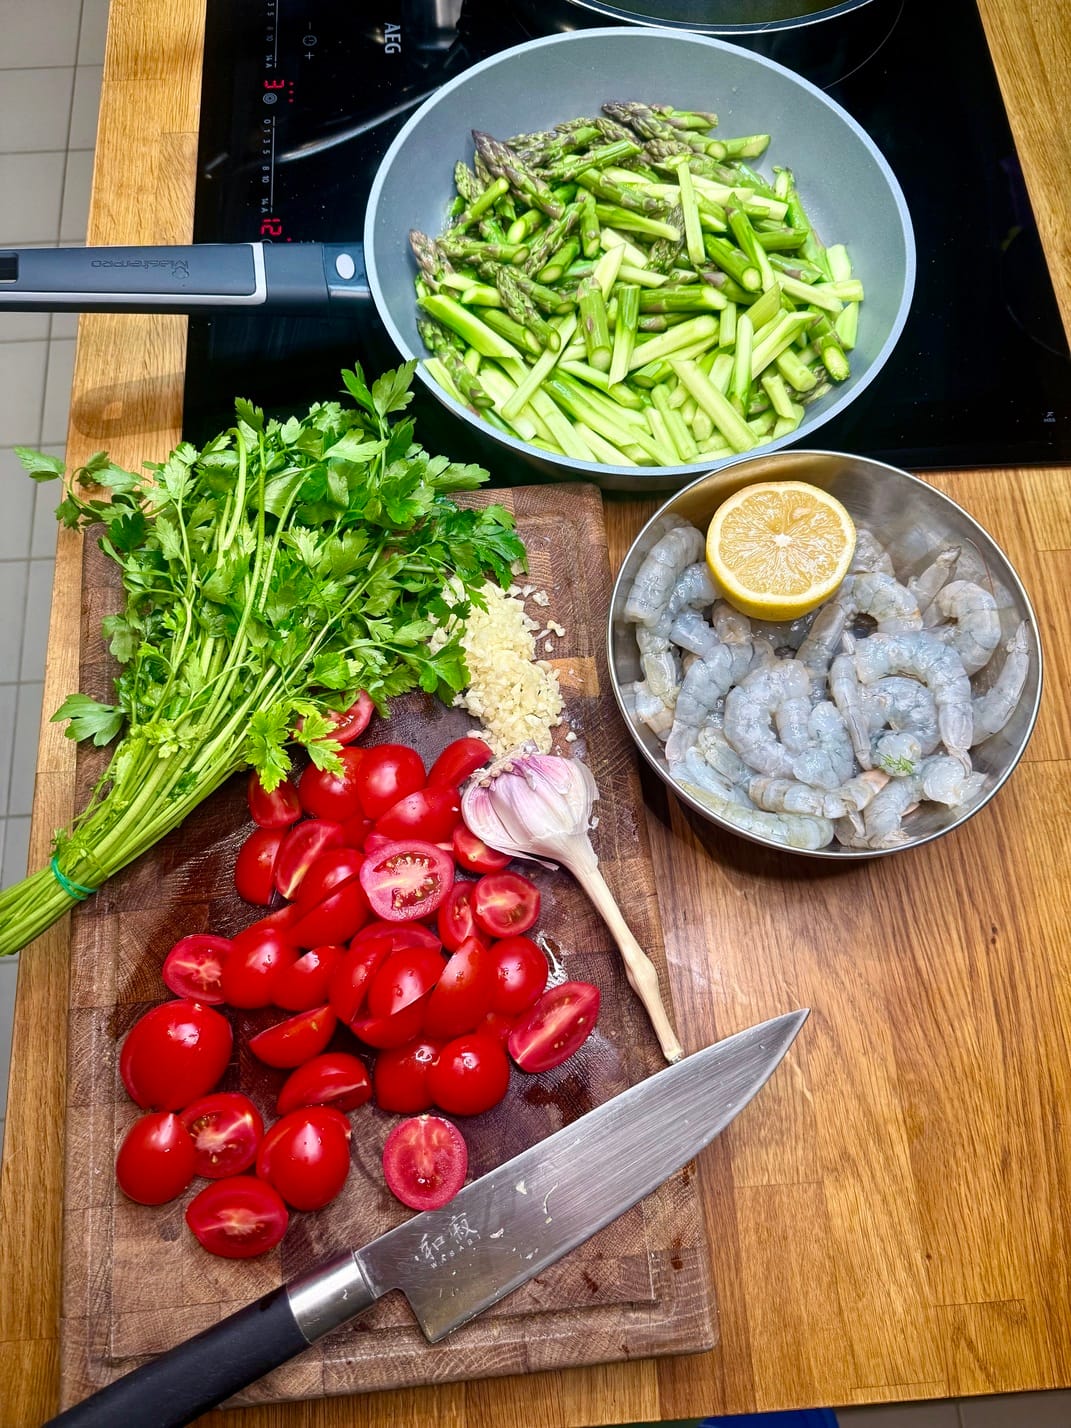
След 5 минути към тях се добавят 300–400 г обелени сурови скариди, три скилидки нарязан чесън, всичко се подправя със сол и черен пипер и се разбърква. След още 3 минути в тигана се добавя една шепа разполовени чери домати, полива се със сока от половин лимон и се поръсва с една връзка нарязан магданоз.

Сервира се с чаша бяло вино и препечен хляб.

Към края на разговора ни към нас се присъединява бащата на Виктор – Атанас, който също е потомствен земеделец, включително и що се отнася до политическата му ориентация. С разочарование споделя за пропиляната енергия от началото на 90-те от страна на БЗНС, който се е радвал на голяма подкрепа в цялата община. Партия, станала жертва на балкански кавги и интриги, размита през годините от недобросъвестни водачи и останала само избледняващ спомен за някогашните надежди и очаквания на хората от малките градове и села на България.

Завръщането на буржоазния зеленчук
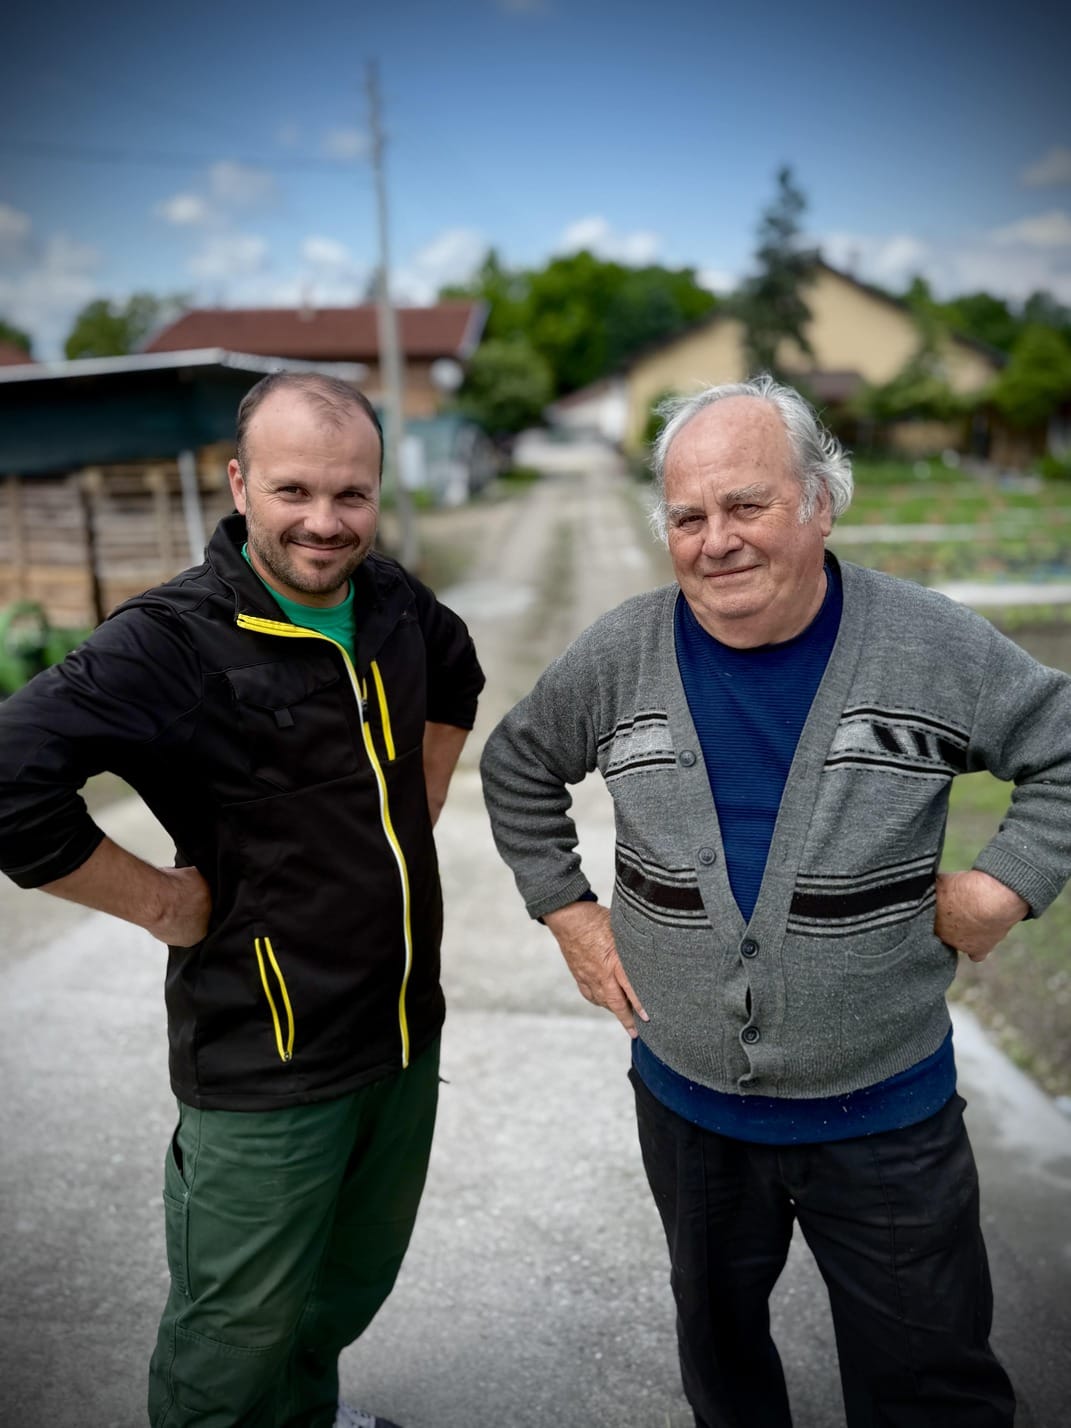
Виктор и Атанас Илиеви. Снимка: © Чило Попов

Някак си мимоходом и накрая Атанас споделя нещо, което ме накара да настръхна, а очите ми да се навлажнят:

Чило, знаеш ли, че още прадядото на Виктор е гледал аспержи тук, в селото? И не само, ами е бил май първият, който ги е засял! А след няколко години са го потърсили от царския дворец и са поръчвали от него за кухнята на двореца!

Ей така, между другото, ми беше съобщен такъв впечатляващ факт, който има значение в много различни посоки, и всичките са хубави. Това не е случайно, казвам си, и трябва да продължи – въпреки всичкия хаос и мръсотия извън този малък балон на привидна нормалност. 


Крем супа от аспержи


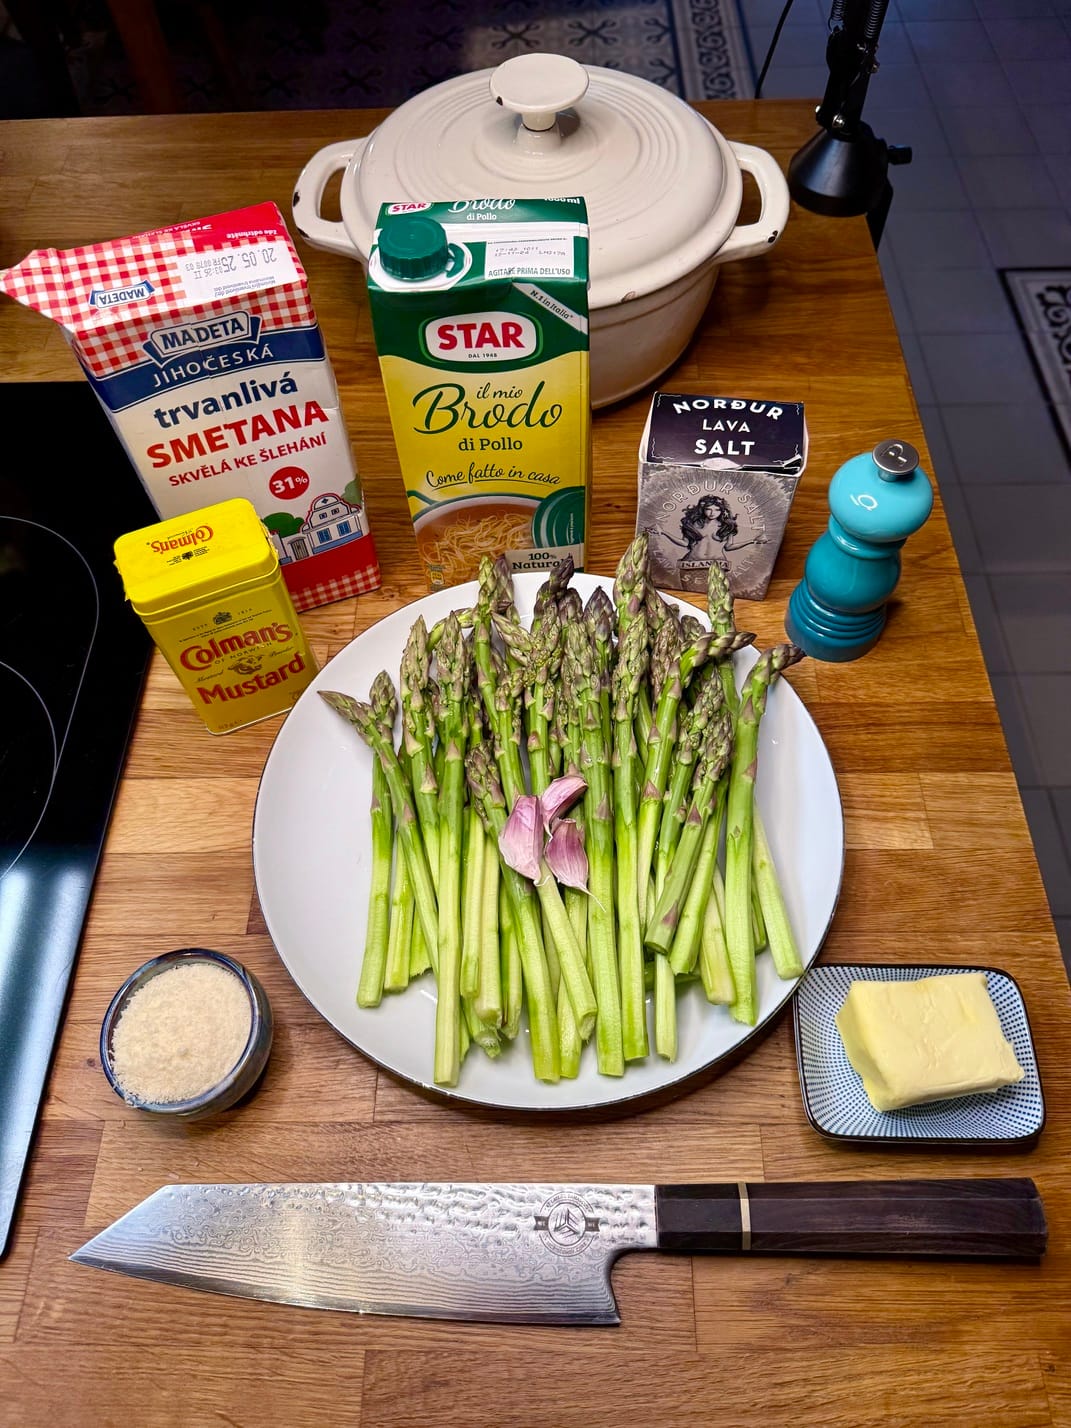
500 г аспержи (една голяма връзка) се измиват и без да се белят или чупят краищата им, се нарязват на едро. Връхчетата на почти всички се отрязват и отделят настрана.

Нарязаните аспержи заедно с две скилидки чесън се варят в 1–1,5 л зеленчуков или пилешки бульон до омекване, а след това сместа се пасира добре и се маха от котлонa.

В тиган с масло се запържват връхчетата на аспержите, докато променят цвета си и не започнат да отделят аромат (за около 3–5 мин.)

Към пасираната смес се добавят 100 мл сметана за готвене, малко горчица на прах и смлян черен пипер.

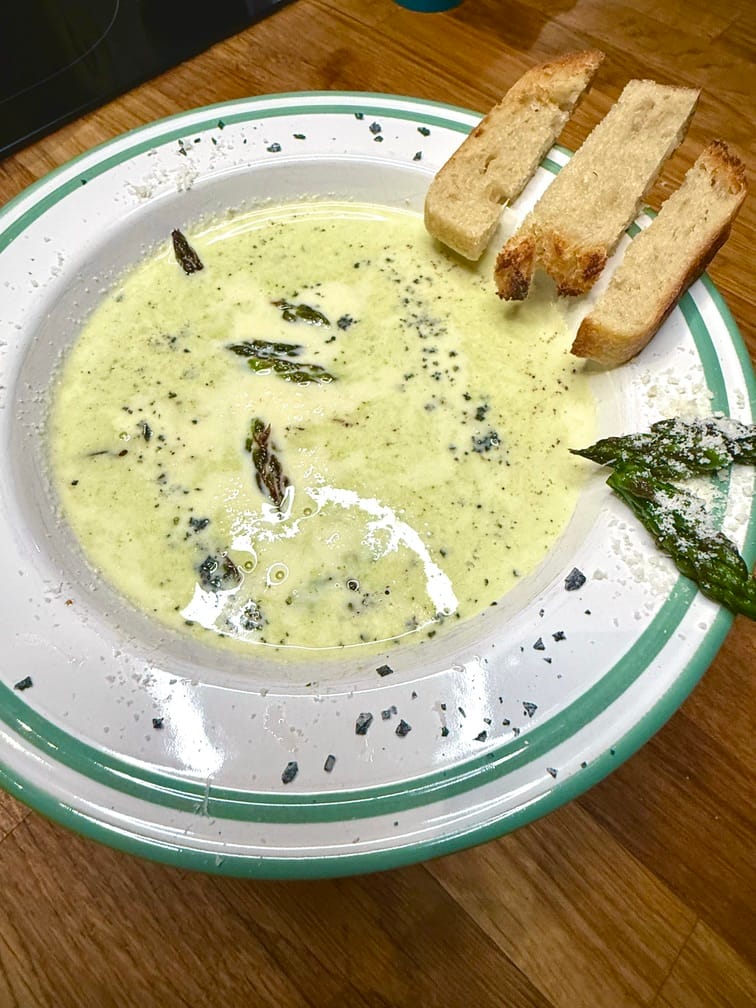
При сервиране супата се поръсва с хрупкавите връхчета на аспержите вместо крутони и с настърган пармезан. Върви също с препечена филийка.

Само си представих, ако това семейство беше в Англия, Германия или Скандинавия, какво би им донесла тази малка история, и то с право. Как подобни семейни ферми, производители на какво ли не, от десетки години се кичат с привилегията да могат да твърдят, че някога са доставяли на двореца по негова поръчка. 

Буржоазният зеленчук рязко получи подплата на претенциите си в моите очи, при това по един съдържателен и чист начин. Чрез благородна скромност. 

* Този надпис видях на Четвъртък пазара в Пловдив и е доказателство, че хората все още се запознават с тази земеделска култура.


 „Вкусната страна“ е поредица на Чило Попов, в която той ни разхожда из България и Балканите, среща ни с производители на храни и продукти и ни води по местата, от които произхождат. Разказва истории за нашето общо минало, настояще и бъдеще през продукти, аромати и вкусове. Всеки разказ ще съдържа и някоя и друга кулинарна рецепта, за да опознаем по-добре вкусната страна на живота.

[$] Allowing BPF programs more access to the network

Post Syndicated from daroc original https://lwn.net/Articles/1022034/

Mahé Tardy led two sessions about some of the challenges that he, Kornilios Kourtis,
and John Fastabend have run into in their work on

Tetragon
(Apache-licensed BPF-based security monitoring software)
at the Linux Storage, Filesystem, Memory Management, and BPF Summit. The session
prompted discussion about the feasibility of letting BPF programs
send data over the network, as well as potential new kfuncs to let BPF firewalls
send TCP reset packets. Tardy presented several possible ways that these could
be accomplished.

[$] System-wide encrypted DNS

Post Syndicated from jzb original https://lwn.net/Articles/1021357/

The increasing sophistication of attackers has organizations
realizing that perimeter-based security models are inadequate. Many
are planning to transition their internal networks to a zero-trust
architecture
. This requires every communication on the network to
be encrypted, authenticated, and authorized. This can be achieved in
applications and services by using modern communication
protocols. However, the world still depends on Domain Name System
(DNS) services where encryption, while possible, is far from being the
industry standard. To address this we, as part of a working group at
Red Hat, worked on fully integrating encrypted DNS for Linux
systems—not only while the system is running but also during the
installation and boot process, including support for a custom
certificate chain in the initial ramdisk. This integration is now
available in CentOS Stream 9, 10, and the upcoming
Fedora 43 release.

Security updates for Wednesday

Post Syndicated from jzb original https://lwn.net/Articles/1022853/

Security updates have been issued by AlmaLinux (gstreamer1-plugins-bad-free and kernel), Arch Linux (bind and varnish), Debian (glibc and syslog-ng), Fedora (microcode_ctl, mozilla-ublock-origin, nodejs20, and nodejs22), Mageia (firefox, nss, rootcerts, open-vm-tools, sqlite3, and thunderbird), Oracle (gstreamer1-plugins-bad-free, kernel, libsoup, nodejs:22, php, php:8.2, php:8.3, python-tornado, redis, and redis:7), Red Hat (libsoup, pcs, and python-tornado), Slackware (mozilla), SUSE (bind, dnsdist, elemental-operator, govulncheck-vulndb, gstreamer-plugins-bad, jetty-annotations, jq, libnss_slurm2, libyelp0, mariadb, nvidia-open-driver-G06-signed, prometheus-blackbox_exporter, python-h11, python-httpcore, python-setuptools, python312, python39-setuptools, screen, sqlite3, umoci, and webkit2gtk3), and Ubuntu (cifs-utils, glibc, linux-aws, linux-intel-iotg-5.15, linux-nvidia-tegra-igx, linux-raspi, linux-aws-fips, linux-hwe-6.8, linux-lowlatency, linux-lowlatency-hwe-6.11, linux-oracle, linux-raspi, linux-raspi-5.4, and net-tools).

Key Takeaways from the Take Command Summit 2025: Customer Panel on Future-Proofing VM Programs

Post Syndicated from Rapid7 original https://blog.rapid7.com/2025/05/28/key-takeaways-from-the-take-command-summit-2025-customer-panel-on-future-proofing-vm-programs/

Key Takeaways from the Take Command Summit 2025: Customer Panel on Future-Proofing VM Programs

One of the most actionable sessions at the Take Command 2025 Virtual Cybersecurity Summit came directly from the field. In a panel hosted by Aniket Menon, VP of Product Management at Rapid7, security leaders from Cross Financial Corp, Phibro Animal Health Corporation, and Miltenyi Biotec shared how they’re evolving vulnerability management into a proactive exposure management strategy.

With real-world examples, team metrics, and shared challenges, the panel offered practical advice for teams ready to modernize their approach and reduce risk with more focus and confidence.

From VM to EM: A shift in mindset

Panelists agreed: traditional vulnerability management practices can’t keep up with today’s dynamic, hybrid environments. To stay ahead, security teams must shift toward continuous exposure assessment – building context around vulnerabilities and aligning efforts with business priorities.

As one attendee later shared in our post-event survey:

“Moving from vulnerability management to exposure management isn’t just a process change – it’s a mindset shift. It forces us to be more proactive.”

This takeaway aligns with broader findings from the summit survey, where 64% of respondents identified exposure management as a top priority for improving their detection and response strategies.

Prioritization requires business context

Volume isn’t the issue – context is. The panel emphasized that real risk reduction happens when teams align remediation priorities with asset value, exploitability, and operational relevance. That means:

  • Building dashboards tailored for different stakeholders
  • Connecting security and IT teams through shared language
  • Using context to elevate urgency and drive action

You can’t fix what you can’t see

Despite tool investments, many organizations still struggle with asset discovery and visibility. In fact, 53% of survey respondents said identifying unknown assets is the most challenging part of exposure management.

As Edward Chang, Senior Manager of Cybersecurity and Compliance at Phibro Animal Health Corporation, explained during the panel:

“No one has 100% visibility. But if we can improve what we see and give that context to the right teams, we’re already ahead of where we were last year.”

The session encouraged using telemetry, automation, and unified data views to close gaps across environments.

Bridging the gap between security and operations

A recurring theme across the panel was the need for collaboration between security, infrastructure, and engineering teams. Effective exposure management doesn’t just rely on the right data — it depends on the right relationships.

Security teams must be integrated into how organizations build, deploy, and operate — not treated as a separate or downstream function. Building that alignment means treating security as an enabler, not a roadblock.

Ownership, accountability, and human risk

Beyond technology, the session also addressed ownership and accountability. Security leaders must not only flag risk — they must clearly assign and communicate responsibility. As attack surfaces expand and teams diversify, the ability to coordinate across functions becomes even more critical.

Watch the full panel on demand

If you’re looking to strengthen your vulnerability management program or build a more proactive exposure management strategy, this session offers a roadmap shaped by real-world experience.

Watch the Customer Panel On Demand

Разследване на Валя Ахчиева: Отломките от взрива в Елин Пелин летели на ….7 км

Post Syndicated from Екип на Биволъ original https://bivol.bg/elin_pelin-explosions_2.html

сряда 28 май 2025


Към 9-те месеца мълчание на всички компетентни и контролни органи за трагедията миналата година край Елин Пелин и взривилите се складове за фойерверки, боеприпаси и огнестрелно оръжие за гражданска употреба,…

Материалът <span style='color:#ff0000;font-size:12px;'>Разследване на Валя Ахчиева:</span> <BR> <H1 class='post-title single-post-title entry-title'>Отломките от взрива в Елин Пелин летели на ….7 км</H1> е публикуван за пръв път на Bivol!.

Location Tracking App for Foreigners in Moscow

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/05/location-tracking-app-for-foreigners-in-moscow.html

Russia is proposing a rule that all foreigners in Moscow install a tracking app on their phones.

Using a mobile application that all foreigners will have to install on their smartphones, the Russian state will receive the following information:

  • Residence location
  • Fingerprint
  • Face photograph
  • Real-time geo-location monitoring

This isn’t the first time we’ve seen this. Qatar did it in 2022 around the World Cup:

“After accepting the terms of these apps, moderators will have complete control of users’ devices,” he continued. “All personal content, the ability to edit it, share it, extract it as well as data from other apps on your device is in their hands. Moderators will even have the power to unlock users’ devices remotely.”

Unlock self-serve streaming SQL with Amazon Managed Service for Apache Flink

Post Syndicated from Sofie Zilberman original https://aws.amazon.com/blogs/big-data/unlock-self-serve-streaming-sql-with-amazon-managed-service-for-apache-flink/

This post is co-written with Gal Krispel from Riskified.

Riskified is an ecommerce fraud prevention and risk management platform that helps businesses optimize online transactions by distinguishing legitimate customers from fraudulent ones.

Using artificial intelligence and machine learning (AI/ML), Riskified analyzes real-time transaction data to detect and prevent fraud while maximizing transaction approval rates. The platform provides a chargeback guarantee, protecting merchants from losses due to fraudulent transactions. Riskified’s solutions include account protection, policy abuse prevention, and chargeback management software, making it a comprehensive tool for reducing risk and enhancing customer experience. Businesses across various industries, including retail, travel, and digital goods, use Riskified to increase revenue while minimizing fraud-related losses. Riskified’s core business of real-time fraud prevention makes low-latency streaming technologies a fundamental part of its solution.

Businesses often can’t afford to wait for batch processing to make critical decisions. With real-time data streaming technologies like Apache Flink, Apache Spark, and Apache Kafka Streams, organizations can react instantly to emerging trends, detect anomalies, and enhance customer experiences. These technologies are powerful processing engines that perform analytical operations at scale. However, unlocking the full potential of streaming data often requires complex engineering efforts, limiting accessibility for analysts and business users.

Streaming pipelines are in high demand from Riskified’s Engineering department. Therefore, a user-friendly interface for creating streaming pipelines is a critical feature to increase analytical precision for detecting fraudulent transactions.

In this post, we present Riskified’s journey toward enabling self-service streaming SQL pipelines. We walk through the motivations behind the shift from Confluent ksqlDB to Apache Flink, the architecture Riskified built using Amazon Managed Service for Apache Flink, the technical challenges they faced, and the solutions that helped them make streaming accessible, scalable, and production-ready.

Using SQL to create streaming pipelines

Customers have a range of open source data processing technologies to choose from, such as Flink, Spark, ksqlDB, and RisingWave. Each platform offers a streaming API for data processing. SQL streaming jobs offer a powerful and intuitive way to process real-time data with minimal complexity. These pipelines use SQL, a widely known and declarative language, to perform real-time transformations, filtering, aggregations, and joins in continuous data streams.

To illustrate the power of streaming SQL in ecommerce fraud prevention, consider the concept of velocity checks, which are a critical fraud detection pattern. Velocity checks are a type of security measure used to detect unusual or rapid activity by monitoring the frequency and volume of specific actions within a given timeframe. These checks help identify potential fraud or abuse by analyzing repeated behaviors that deviate from normal user patterns. Common examples include detecting multiple transactions from the same IP address in a short time span, monitoring bursts of account creation attempts, or tracking the repeated use of a single payment method across different accounts.

Use case: Riskified’s velocity checks

Riskified implemented a real-time velocity check using streaming SQL to monitor purchasing behavior based on user identifier.

In this setup, transaction data is continuously streamed through a Kafka topic. Each message contains user agent information originating from the browser, along with the raw transaction data. Streaming SQL queries are used to aggregate the number of transactions originating from a single user identifier within short time windows.

For example, if the number of transactions from a given user identifier exceeds a certain threshold within a 10-second period, this might signal fraudulent activity. When that threshold is breached, the system can automatically flag or block the transactions before they are completed. The following figure and accompanying code provide a simplified example of the streaming SQL query used to detect this behavior.

Velocity check SQL flow

SELECT userIdentifier,TUMBLE_START(createdAt, INTERVAL '10' SECONDS) 
  AS windowStart,TUMBLE_END(createdAt, INTERVAL '10' SECONDS) 
  AS windowEnd, COUNT(*) AS paymentAttempts
FROM transactions
  WINDOW TUMBLING (SIZE 10 SECONDS)
GROUP BY userIdentifier;

Although defining SQL queries over static datasets might appear straightforward, developing and maintaining robust streaming applications introduces unique challenges. Traditional SQL operates on bounded datasets, which are finite collections of data stored in tables. In contrast, streaming SQL is designed to process continuous, unbounded data streams resembling the SQL syntax.

To address these challenges at scale and make streaming job creation accessible to engineering teams, Riskified implemented a self-serve solution based on Confluent ksqlDB, using its SQL interface and built-in Kafka integration. Engineers could define and deploy streaming pipelines using SQL, chaining ksqlDB streams from source to sink. The system supported both stateless and stateful processing directly on Kafka topics, with Avro schemas used to define the structure of streaming data.

Although ksqlDB provided a fast and approachable starting point, it eventually revealed several limitations. These included challenges with schema evolution, difficulties in managing compute resources, and the absence of an abstraction for managing pipelines as a cohesive unit. As a result, Riskified began exploring alternative technologies that could better support its expanding streaming use cases. The following sections outline these challenges in more detail.

Evolving the stream processing architecture

In evaluating alternatives, Riskified focused on technologies that could address the specific demands of fraud detection while preserving the simplicity that made the original approach appealing. The team encountered the following challenges in maintaining the previous solution:

  • Schemas are managed in Confluent Schema Registry, and the message format is Avro with FULL compatibility mode enforced. Schemas are constantly evolving according to business requirements. They are version controlled using Git with a strict continuous integration and continuous delivery (CI/CD) pipeline. As schemas grew more complex, ksqlDB’s approach to schema evolution didn’t automatically incorporate newly added fields. This behavior required dropping streams and recreating them to add new fields instead of just restarting the application to incorporate new fields. This approach caused inconsistencies with offset management due to the stream’s tear-down.
  • ksqlDB enforces a TopicNameStrategy schema registration strategy, which provides 1:1 schema-to-topic coupling. This means the exact schema definition has to be registered multiple times, one time for each topic it is used for. Riskified’s schema registry deployment uses RecordNameStrategy for schema registration. It’s an efficient schema registry strategy that allows for sharing schemas across multiple topics, storing fewer schemas, and reducing registry management overhead. Having mixed strategies in the schema registry caused errors with Kafka consumer clients attempting to decode messages, because the client implementation expected a RecordNameStrategy according to Riskified’s standard.
  • ksqlDB internally registers schema definitions in specific ways where fields are interpreted as nullable, and Avro Enum types are converted to Strings. This behavior caused deserialization errors when attempting to migrate native Kafka consumer applications to use the ksqlDB output topic. Riskified’s code base uses the Scala programming language, where optional fields in the schema are interpreted as Option. Transforming every field as optional in the schema definition required heavy refactoring, treating all Enum fields as Strings, and handling the Option data type for every field that requires safe handling. This cascading effect made the migration process more involved, requiring additional time and resources to achieve a smooth transition.

Managing resource contention in ksqlDB streaming workloads

ksqlDB queries are compiled into a Kafka Streams topology. The query definition defines the topology’s behavior.

Streaming query resources are shared rather than isolated. This approach typically leads to the overallocation of cluster resources. Its tasks are distributed across nodes in a ksqlDB cluster. This architecture means processing tasks with no resource isolation, and a specific task can impact other tasks running on the same node.

Resource contention between tasks on the same node is common in a production-intensive environment when using a cluster architecture solution. Operation teams often fine-tune cluster configurations to maintain acceptable performance, frequently mitigating issues by over-provisioning cluster nodes.

Challenges with ksqlDB pipelines

A ksqlDB pipeline is a chain of individual streams and lacks flow-level abstraction. Imagine a complex pipeline where a consumer publishes to multiple topics. In ksqlDB, each topic (both input and output) must be managed as a separate stream abstraction. However, there is no high-level abstraction to represent an entire pipeline that chains these streams together. As a result, engineering teams must manually assemble individual streams into a cohesive data flow, without built-in support for managing them as a single, complete pipeline.

This architectural approach particularly impacts operational tasks. Troubleshooting requires examining each stream separately, making it difficult to monitor and maintain pipelines that contain dozens of interconnected streams. When issues occur, the health of each stream needs to be checked individually, with no logical data flow component to help understand the relationships between streams or their role in the overall pipeline. The absence of a unified view of the data flow significantly increased operational complexity.

Flink as an alternative

Riskified began exploring alternatives for its streaming platform. The requirements were clear: a strong processing technology that combines a rich low-level API and a streaming SQL engine, backed by a strong open source community, proven to perform in the most demanding production environments.

Unlike the previous solution, which supported only Kafka-to-Kafka integration, Flink offers an array of connectors for various databases and Streaming platforms. It was quickly recognized that Flink had the potential to handle complex streaming use cases.

Flink offers multiple deployment options, including standalone clusters, native Kubernetes deployments using operators, and Hadoop YARN clusters. For enterprises seeking a fully managed option, cloud providers like AWS offer managed Flink services that help alleviate operational overhead, such as Managed Service for Apache Flink.

Benefits of using Managed Service for Apache Flink

Riskified decided to implement a solution using Managed Service for Apache Flink. This choice offered several key advantages:

  • It offers a quick and reliable way to run Flink applications and reduces the operational overhead of independently managing the infrastructure.
  • Managed Service for Apache Flink provides true job isolation by running each streaming application in its dedicated cluster. This means you can manage resources separately for each job and reduce the risk of heavy streaming jobs inflicting resource starvation for other running jobs.
  • It offers built-in monitoring using Amazon CloudWatch metrics, application state backup with managed snapshots, and automatic scaling.
  • AWS offers comprehensive documentation and practical examples to help accelerate the implementation process.

With these features, Riskified could focus on what truly matters—getting closer to the business goal and starting to write applications.

Using Flink’s streaming SQL engine

Developers can use Flink to build complex and scalable streaming applications, but Riskified saw it as more than just a tool for experts. They wanted to democratize the power of Flink into a tool for the entire organization, to solve complex business challenges involving real-time analytics requirements without needing a dedicated data professional.

To replace their previous solution, they envisioned maintaining a “build once, deploy many” application, which encapsulates the complexity of the Flink programming and allows the users to focus on the SQL processing logic.

Kafka was maintained as the input and output technology for the initial migration use case, which is similar to the ksqlDB setup. They designed a single, flexible Flink application where end-users can modify the input topics, SQL processing logic, and output destinations through runtime properties. Although ksqlDB primarily focuses on Kafka integration, Flink’s extensive connector ecosystem enables it to expand to diverse data sources and destinations in future phases.

Managed Service for Apache Flink provides a flexible way to configure streaming applications without modifying their code. By using runtime parameters, you can change the application’s behavior without modifying its source code.

Using Managed Service for Apache Flink for this approach includes the following steps:

  1. Apply parameters for the input/output Kafka topic, a SQL query, and the input/output schema ID (assuming you’re using Confluent Schema Registry).
  2. Use AvroSchemaConverter to convert an Avro schema into a Flink table.
  3. Apply the SQL processing logic and save the output as a view.
  4. Sink the view results into Kafka.

The following diagram illustrates this workflow.
Streaming SQL system diagram

Performing Flink SQL query compilation without a Flink runtime environment

Providing end-users with significant control to define their pipelines makes it critical to verify the SQL query defined by the user before deployment. This validation prevents failed or hanging jobs that could consume unnecessary resources and incur unnecessary costs.

A key challenge was validating Flink SQL queries without deploying the full Flink runtime. After investigating Flink’s SQL implementation, Riskified discovered its dependency on Apache Calcite – a dynamic data management framework that handles SQL parsing, optimization, and query planning independently of data storage. This insight enabled using Calcite directly for query validation before job deployment.

You must know how the data is structured to validate a Flink SQL query on a streaming source like a Kafka topic. Otherwise, unexpected errors might occur when attempting to query the streaming source. Although an expected schema is used with relational databases, it’s not enforced for streaming sources.

Schemas guarantee a deterministic structure for the data stored in a Kafka topic when using a schema registry. A schema can be materialized into a Calcite table that defines how data is structured in the Kafka topic. It allows inferring table structures directly from schemas (in this case, Avro format was used), enabling thorough field-level validation, including type checking and field existence, all before job deployment. This table can later be used to validate the SQL query.

The following code is an example of supporting basic field types validation using Calcite’s AbstractTable:

public class FlinkValidator {
    public static void validateSQL(String sqlQuery, Schema avroSchema) throws Exception {
        SqlParser.Config sqlConfig = SqlParser.config()
                .withCaseSensitive(true);
        SqlParser sqlParser = SqlParser.create(sqlQuery, sqlConfig);
        SqlNode parsedQuery = sqlParser.parseQuery();
        RelDataTypeFactory typeFactory = new SqlTypeFactoryImpl(RelDataTypeFactory.DEFAULT);
        CalciteSchema rootSchema = createSchemaWithAvro(avroSchema);
        SqlValidator validator = SqlValidatorUtil.newValidator(
                Frameworks.newConfigBuilder().build().getOperatorTable(),
                rootSchema.createCatalogReader(Collections.emptyList(), typeFactory),
                typeFactory,
                SqlValidator.Config.DEFAULT
        );
        validator.validate(parsedQuery);
    }
    private static CalciteSchema createSchemaWithAvro(Schema avroSchema) {
        CalciteSchema rootSchema = CalciteSchema.createRootSchema(true);
        rootSchema.add("TABLE", new SimpleAvroTable(avroSchema));
        return rootSchema;
    }
    private static class SimpleAvroTable extends org.apache.calcite.schema.impl.AbstractTable {
        private final Schema avroSchema;
        public SimpleAvroTable(Schema avroSchema) {
            this.avroSchema = avroSchema;
        }
        @Override
        public RelDataType getRowType(RelDataTypeFactory typeFactory) {
            RelDataTypeFactory.Builder builder = typeFactory.builder();
            for (Schema.Field field : avroSchema.getFields()) {
                builder.add(field.name(), convertAvroType(field.schema(), typeFactory));
            }
            return builder.build();
        }
        private RelDataType convertAvroType(Schema schema, RelDataTypeFactory typeFactory) {
            switch (schema.getType()) {
                case STRING:
                    return typeFactory.createSqlType(SqlTypeName.VARCHAR);
                case INT:
                    return typeFactory.createSqlType(SqlTypeName.INTEGER);
                default:
                    return typeFactory.createSqlType(SqlTypeName.ANY);
            }
        }
    }
}

You can integrate this validation approach as an intermediate step before creating the application. You can create a streaming job programmatically with the AWS SDK, AWS Command Line Interface (AWS CLI), or Terraform. The validation occurs before submitting the streaming job.

Flink SQL and Confluent Avro data type mapping limitation

Flink provides several APIs designed for different levels of abstraction and user expertise:

  • Flink SQL sits at the highest level, allowing users to express data transformations using familiar SQL syntax, which is ideal for analysts and teams comfortable with relational concepts.
  • The Table API offers a similar approach but is embedded in Java or Python, enabling type-safe and more programmatic expressions.
  • For more control, the DataStream API exposes low-level constructs to manage event time, stateful operations, and complex event processing.
  • At the most granular level, the ProcessFunction API provides full access to Flink’s runtime features. It’s suitable for advanced use cases that demand detailed control over state and processing behavior.

Riskified initially used the Table API to define streaming transformations. However, when deploying their first Flink job to a staging environment, they encountered serialization errors related to the avro-confluent library and Table API. Riskified’s schemas rely heavily on Avro Enum types, which the avro-confluent integration doesn’t fully support. As a result, Enum fields were converted to Strings, leading to mismatches during serialization and errors when attempting to sink processed data back to Kafka using Flink’s Table API.

Riskified developed an alternative approach to overcome the Enum serialization limitations while maintaining schema requirements. They discovered that Flink’s DataStream API could correctly handle Confluent’s Avro records serialization with Enum fields, unlike the Table API. They implemented a hybrid solution combining both APIs because the pipeline only required SQL processing on the source Kafka topic. It can sink to the output without any additional processing. The Table API is used for data processing and transformations, only converting to the DataStream API at the final output stage.

Managed Service for Apache Flink supports Flink APIs. It can switch between the Table API and the DataStream API.
A MapFunction can convert the Row type of the Table API into a DataStream of GenericRecord. The MapFunction maps Flink’s Row data type into GenericRecord types by iterating over the Avro schema fields and building the GenericRecord from the Flink Row type, casting the Row fields into the correct data type according to the Avro schema. This conversion is required to overcome the avro-confluent library limitation with Flink SQL.

The following diagram and illustrates this workflow.

Flink Table and DataStream APIs

The following code is an example query:

// SQL Query for filtering
Table queryResults = tableEnv.sqlQuery(
       "SELECT * FROM InputTable");
// 1. Convert query results from Table API to a DataStream<Row> and use DataStream API to sink query results to Kafka topic
DataStream<Row> rowStream = tableEnv.toDataStream(queryResults);
// Fetch the schema string from the schema registry
String schemaString = fetchSchemaString(schemaRegistryURL, schemaSubjectName);
// 2. Convert Row to GenericRecord with explicit TypeInformation, using custom AvroMapper
TypeInformation<GenericRecord> typeInfo = new GenericRecordAvroTypeInfo(avroSchema);
DataStream<GenericRecord> genericRecordStream = rowStream
       .map(new AvroMapper(schemaString))
       .returns(typeInfo); // Explicitly set TypeInformation
// 3. Define Kafka sink using ConfluentRegistryAvroSerializationSchema
KafkaSink<GenericRecord> kafkaSink = KafkaSink.<GenericRecord>builder()
       .setBootstrapServers(bootstrapServers)
       .setRecordSerializer(
               KafkaRecordSerializationSchema.builder()
                       .setTopic(sinkTopic)
                       .setValueSerializationSchema(
                               ConfluentRegistryAvroSerializationSchema.forGeneric(
                                       schemaSubjectName,
                                       avroSchema,
                                       schemaRegistryURL
                               )
                       )
                       .build()
       )
       .build();
// Sink to Kafka
genericRecordStream.sinkTo(kafkaSink);

CI/CD With Managed Service for Apache Flink

With Managed Service for Apache Flink, you can run a job by selecting an Amazon Simple Storage Service (Amazon S3) key containing the application JAR. Riskified’s Flink code base was structured as a multi-module repository to support additional use cases besides supporting self-service SQL. Each Flink job source code in the repository is an independent Java module. The CI pipeline implemented a robust build and deployment process consisting of the following steps:

  1. Build and compile each module.
  2. Run tests.
  3. Package the modules.
  4. Upload the artifact to the artifacts bucket twice: one JAR under <module>-<version>.jar and the second as <module>-latest.jar, resembling a Docker registry like Amazon Elastic Container Registry (Amazon ECR). Managed Service for Apache Flink jobs uses the latest tag artifact in this case. However, a copy of old artifacts is kept for code rollback reasons.

A CD process follows this process:

  1. When merged, it lists all jobs for each module using the AWS CLI for Managed Service for Apache Flink.
  2. The application JAR location is updated for each application, which triggers a deployment.
  3. When the application is in a running state with no errors, the following application will be continued.

To allow safe deployment, this process is done gradually for every environment, starting with the staging environment.

Self-service interface for submitting SQL jobs

Riskified believes an intuitive UI is crucial for system adoption and efficiency. However, developing a dedicated UI for Flink job submission requires a pragmatic approach, because it might not be worth investing in unless there’s already a web interface for internal development operations.

Investing in UI development should align with the organization’s existing tools and workflows. Riskified had an internal web portal for similar operations, which made the addition of Flink job submission capabilities a natural extension of the self-service infrastructure.

An AWS SDK was installed on the web server to allow interaction with AWS components. The client receives user input from the UI and translates it into runtime properties to adjust the behavior of the Flink application. The web server then uses the CreateApplication API action to submit the job to Managed Service for Apache Flink.

Although an intuitive UI significantly enhances system adoption, it’s not the only path to accessibility. Alternatively, a well-designed CLI tool or REST API endpoint can provide the same self-service capabilities.

The following diagram illustrates this workflow.

Flow sequence diagram

Production experience: Flink’s implementation upsides

The transition to Flink and Managed Service for Apache Flink proved efficient in numerous aspects:

  • Schema evolution and data handling – Riskified can either periodically fetch updated schemas or restart applications when schemas evolve. They can use existing schemas without self-registration.
  • Resource isolation and management – Managed Service for Apache Flink runs each Flink job as an isolated cluster, reducing resource contention between jobs.
  • Resource allocation and cost-efficiency – Managed Service for Apache Flink enables minimum resource allocation with automatic scaling, proving to be more cost-efficient.
  • Job management and flow visibility – Flink provides a cohesive data flow abstraction through its job and task model. It manages the entire data flow in a single job and distributes the workload evenly over multiple nodes. This unified approach enables better visibility into the entire data pipeline, simplifying monitoring, troubleshooting, and optimizing complex streaming workflows.
  • Built-in recovery mechanism – Managed Service for Apache Flink automatically creates checkpoints and savepoints that enable stateful Flink applications to recover from failures and resume processing without data loss. With this feature, streaming jobs are durable and can recover safely from errors.
  • Comprehensive observability – Managed Service for Apache Flink exposes CloudWatch metrics that monitor Flink application performance and statistics. You can also create alarms based on these metrics. Riskfied decided to use the Cloudwatch Prometheus Exporter to export these metrics to Prometheus and build PrometheusRules to align Flink’s monitoring to the Riskified standard, which uses Prometheus and Grafana for monitoring and alerting.

Next steps

Although the initial focus was Kafka-to-Kafka streaming queries, Flink’s wide range of sink connectors offers the possibility of pluggable multi-destination pipelines. This versatility is on Riskfied’s roadmap for future enhancements.

Flink’s DataStream API provides capabilities that extend far beyond self-serving streaming SQL capabilities, opening new avenues for more sophisticated fraud detection use cases. Riskified is exploring ways to use DataStream APIs to enhance ecommerce fraud prevention strategies.

Conclusions

In this post, we shared how Riskified successfully transitioned from ksqlDB to Managed Service for Apache Flink for its self-serve streaming SQL engine. This move addressed key challenges like schema evolution, resource isolation, and pipeline management. Managed Service for Apache Flink offers features such as including isolated jobs environments, automatic scaling, and built-in monitoring, which proved more efficient and cost-effective. Although Flink SQL limitations with Kafka required workarounds, using Flink’s DataStream API and user-defined functions resolved these issues. The transition has paved the way for future expansion with multi-targets and advanced fraud detection capabilities, solidifying Flink as a robust and scalable solution for Riskified’s streaming needs.

If Riskified’s journey has sparked your interest in building a self-service streaming SQL platform, here’s how to get started:


About the authors

Gal Krispel is a Data Platform Engineer at Riskified, specializing in streaming technologies such as Apache Kafka and Apache Flink. He focuses on building scalable, real-time data pipelines that power Riskified’s core products. Gal is particularly interested in making complex data architectures accessible and efficient across the organization. His work spans real-time analytics, event-driven design, and the seamless integration of stream processing into large-scale production systems.

Sofia ZilbermanSofia Zilberman works as a Senior Streaming Solutions Architect at AWS, helping customers design and optimize real-time data pipelines using open-source technologies like Apache Flink, Kafka, and Apache Iceberg. With experience in both streaming and batch data processing, she focuses on making data workflows efficient, observable, and high-performing.

Lorenzo NicoraLorenzo Nicora works as Senior Streaming Solution Architect at AWS, helping customers across EMEA. He has been building cloud-centered, data-intensive systems for over 25 years, working across industries both through consultancies and product companies. He has used open-source technologies extensively and contributed to several projects, including Apache Flink, and is the maintainer of the Flink Prometheus connector.

Auras Shows Next-Gen Intel Oak Stream Cold Plates at Computex 2025

Post Syndicated from Cliff Robinson original https://www.servethehome.com/auras-shows-next-gen-intel-oak-stream-cold-plates-at-computex-2025/

At Computex 2025, we saw Intel Oak Stream liquid cooling cold plates for next-generation Intel Xeon processors

The post Auras Shows Next-Gen Intel Oak Stream Cold Plates at Computex 2025 appeared first on ServeTheHome.

The collective thoughts of the interwebz