Tag Archives: Uncategorized

A Device to Turn Traffic Lights Green

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/a-device-to-turn-traffic-lights-green.html

Here’s a story about a hacker who reprogrammed a device called “Flipper Zero” to mimic Opticom transmitters—to turn traffic lights in his path green.

As mentioned earlier, the Flipper Zero has a built-in sub-GHz radio that lets the device receive data (or transmit it, with the right firmware in approved regions) on the same wireless frequencies as keyfobs and other devices. Most traffic preemption devices intended for emergency traffic redirection don’t actually transmit signals over RF. Instead, they use optical technology to beam infrared light from vehicles to static receivers mounted on traffic light poles.

Perhaps the most well-known branding for these types of devices is called Opticom. Essentially, the tech works by detecting a specific pattern of infrared light emitted by the Mobile Infrared Transmitter (MIRT) installed in a police car, fire truck, or ambulance when the MIRT is switched on. When the receiver detects the light, the traffic system then initiates a signal change as the emergency vehicle approaches an intersection, safely redirecting the traffic flow so that the emergency vehicle can pass through the intersection as if it were regular traffic and potentially avoid a collision.

This seems easy to do, but it’s also very illegal. It’s called “impersonating an emergency vehicle,” and it comes with hefty penalties if you’re caught.

Using Porting Advisor for Graviton

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/using-porting-advisor-for-graviton/

This blog post is written by Ryan Doty Solutions Architect , AWS and Vishal Manan Sr. SSA, EC2 Graviton , AWS.

Introduction

AWS customers recognize that Graviton-based EC2 instances deliver price-performance benefits but many are concerned about the effort to port existing applications. Porting code from one architecture to another can result in a substantial investment in time and effort. AWS has worked continuously to improve the migration process for customers. We recently introduced the Porting Advisor for Graviton as a tool to further simplify the migration process. In this blog, we’ll walk you through how to use Porting Advisor for Graviton so that you can learn how to use it.

Porting Advisor for Graviton is an open-source, command-line tool that analyzes source code and generates a report highlighting missing or outdated libraries and code constructs that may require modification and provides a user with alternative recommendations. It helps customers and developers accelerate their transition to Graviton-based Amazon EC2 instances by reducing the iterative process of identifying and resolving source code and library dependencies. This blog post will provide you with a step-by-step implementation on how to use Porting Advisor for Graviton. At the end of the blog, you will be able to run Porting Advisor for Graviton on your source code tree, generating findings that will help simplify the effort required to port your application.

Porting Advisor for Graviton scans for potentially unsupported or non-portable arm64 code in source code trees. The tool only scans source code files for the programming languages C/C++, Fortran, Go 1.11+, Java 8+, Python 3+, and dependency files such as project/requirements.txt file(s). Most importantly the Porting Advisor doesn’t make any code modifications, API-level recommendations, or send data back to AWS.

You can utilize Porting Advisor for Graviton either as a Python script or compiled into a binary and run on x86-64 or arm64 systems. Therefore, it can be easily implemented as part of your build processes.

Expected Results

Porting Advisor for Graviton reports the following issues:

  1. Inline assembly with no corresponding arm64 inline assembly.
  2. Assembly source files with no corresponding arm64 assembly source files.
  3. Missing arm64 architecture detection in autoconf config.guess scripts.
  4. Linking against libraries that aren’t available on the arm64 architecture.
  5. Use  architecture specific intrinsics.
  6. Preprocessor errors that trigger when compiling on arm64.
  7. Usages of old Visual C++ runtime (Windows specific).

Compiler specific code guarded by compiler specific pre-defined macros is detected, but not reported by default. The following cross-compile specific issues are detected, but not reported by default:

  • Architecture detection that depends on the host rather than the target.
  • Use of build artifacts in the build process.

Skillsets needed for using the tool

Porting Advisor for Graviton is designed to be easy to use. Users though should be versed in the following skills in order to take advantage of the recommendations the tool provides:

  • An understanding of the build system – project requirements and dependencies, versioning, etc.
  • Basic scripting language skills around Python, PowerShell/Bash.
  • Understanding hardware (inline assembly for C/C++) or compiler specific (intrinsic for C/C++) constructs when applicable.
  • The ability to follow best practices in the AWS Graviton Technical Guide for code optimization.

How to use Porting Advisor for Graviton

Prerequisites

The tool requires a minimum version of Python 3.10 and Java (8+ to be installed). The installation of Java is also optional and only required if you want to scan JAR files for native method calls. You can run the tool on a Windows/Linux/MacOS machine, or in an EC2 instance. I will show case usage on Windows and Amazon Linux 2(AL2) running on an EC2 instance. It supports both arm64 and x86-64 processors.

You don’t need to be on an arm64-based processor to run the tool.

The tool doesn't need a lot of CPU Horsepower and even a system with few processors will do

You can run the tool as a Python script or an executable. The executable requires extra steps to build. However, it can be used on another machine without the need to install Python packages.

You must copy the complete “dist” folder for it to work, as there are libraries that are present in that folder along with the executable.

Porting Advisor for Graviton can be run as a binary or as a script. You must run the script to generate the binaries

./porting-advisor-linux-x86_64 ~/my/path/to/my/repo --output report.html 
./porting-advisor-linux-x86_64.exe ../test/CppCode/inline_assembly --output report.html

Running Porting Advisor for Graviton as an executable

The first step is to build the executable.

Building the executable

The first step is to set up the Python Environment. If you run into any errors building the binary, see the Troubleshooting section for more details.

Building the binary on Windows

Building Porting Advisor using Powershell

Building Porting Advisor binary

Building the binary on Linux/Mac

Using shell script to build on Linux or macOS

Porting Advisor binary saved in dist folder

Running the binary

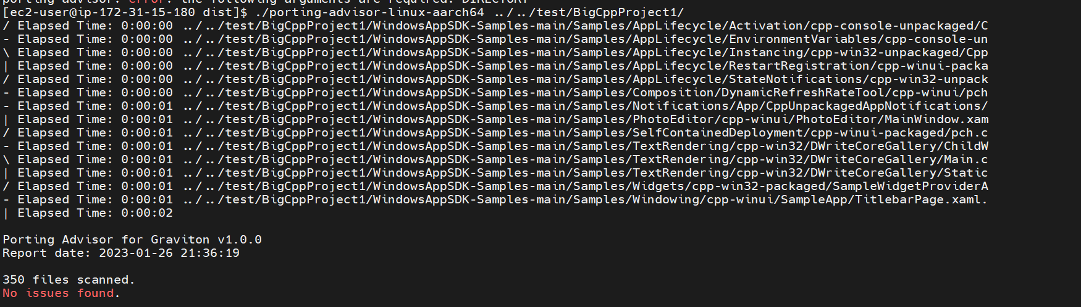
Here you can see how you can run the tool on Linux as a binary for a C++ project.

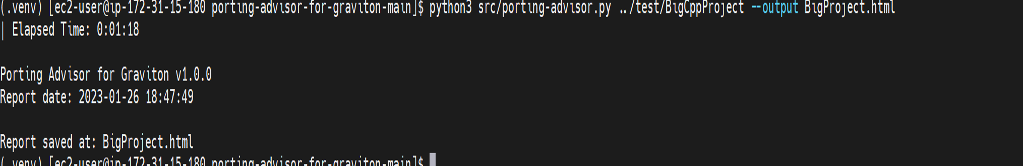
Porting advisor binary run on a C++ codebase with 350 files

The “dist” folder will have the executable.

Running Porting Advisor for Graviton as a script

Enable the Python environment for the following:

Linux/Mac:

$. python3 -m venv .venv
$. source .venv/bin/activate

PowerShell:

PS> python -m venv .venv
PS> .\.venv\Scripts\Activate.ps1

The following shows how the tool would work on Windows when run as a script:

Running Porting Advisor on Windows as a powershell script

Running the Porting Advisor for Graviton on Linux as a Script

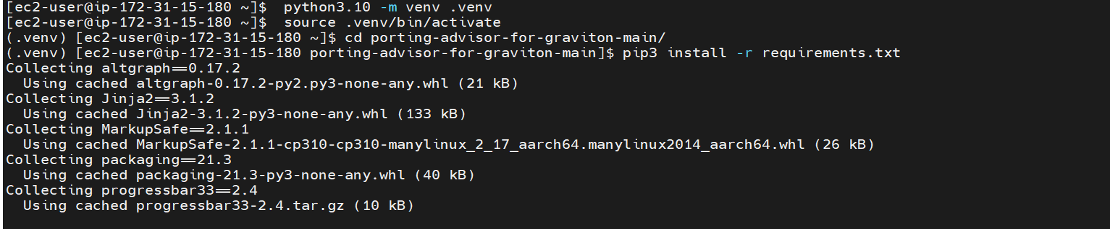
Setting up Python environment to run the Porting Advisor as a script

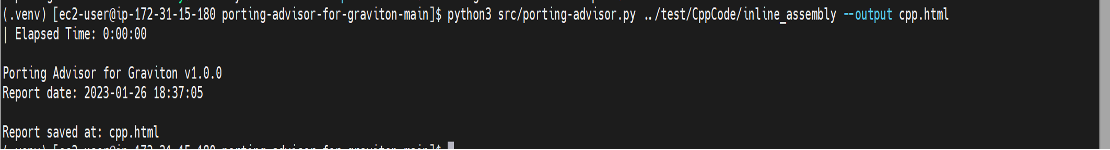
Running Porting Advisor on Linux as a script

Output of the Porting Advisor for Graviton

The Porting Advisor for Graviton requires the directory parameter to point to the folder where your source code lives. If there are multiple locations, then you can run the tool as part of the script.

If no output file is supplied only standard output will be produced. The following is the output of the tool in HTML format. The first line shows the total files scanned.

  1. If no issues are found, then you’ll see an output like the following:

Results of Porting Advisor run on C++ code with 2836 files with no issues found

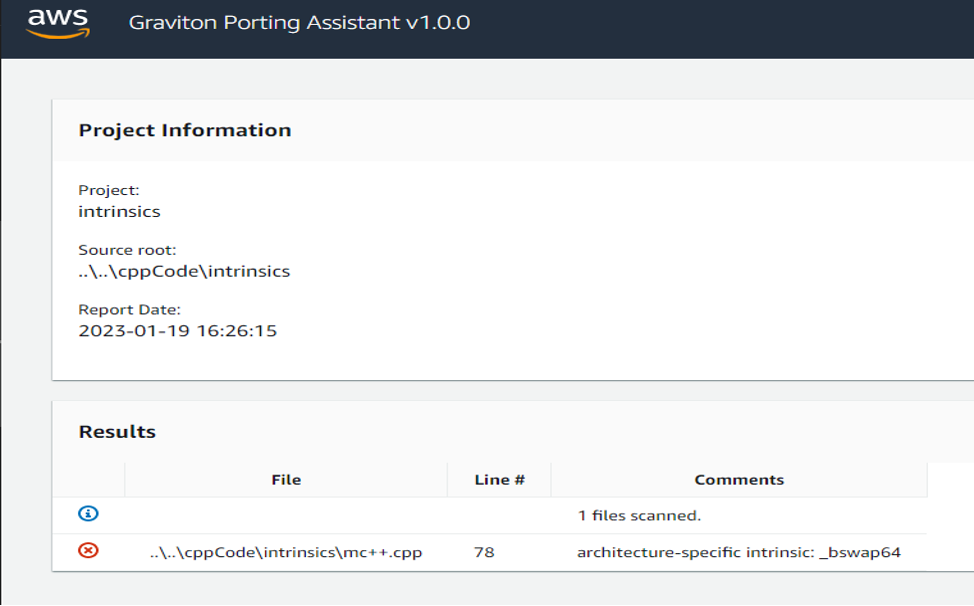
  1. With x86-64 specific intrinsics, such as _bswap64, you’ll see it flagged. arm64 specific intrinsics won’t be flagged. Therefore, if your code has arm64 specific intrinsics, then the porting advisor will only flag x86-64 to arm64 and not vice versa. The primary goal of the tool is determining the arm64 readiness of your code.

Porting Advisor reporting inline assembly files in C++ code

  1. The scanner typically looks for source code files only, but it can also look for assembly files with *.s extensions. An example of a file with the C++ code with inline assembly code is as follows:

Porting Advisor reporting use of intrinsics in C++ code

  1. The tool has pointed out errors such as a preprocessor error and architecture-specific intrinsic usage errors.

Porting Advisor results run on C++ code pointing out missing preprocessor macros for arm64 and x86-64 specific intrinsics

Next steps

If you don’t see any issues reported by the tool, then you are in good shape for doing the port. If no issues are reported it does not guarantee that it will work as port. Porting Advisor for Graviton is a tool used best as a helper. Regardless of the issues reported by the tool, we still highly suggest testing the application thoroughly.

As a good practice, we recommend that you use the latest version of your libraries.

Based on the issue, you can consider further actions. For Compiler intrinsic errors, we recommend studying Intel and arm64 intrinsics.

Once you’ve migrated your code and are using Gravition, you can start to look at taking steps to optimize your performance. If you’re interested in doing that please look at our Getting Started Guide.

If you run into any issues, then see our CONTRIBUTING file.

FAQs

  1. How fast is the tool? The tool is able to scan 4048 files in 1.18 seconds.

On an arm64 Based Instance:

Porting Advisor scans 4048 files in 1.18 seconds

  1. False Positives?

This tool scans all files in a source tree, regardless of whether they are included by the build system or not. Therefore, it may misreport issues in files that appear in the source tree but are excluded by the build system. Currently, the tool supports the following languages/dependencies: C/C++, Fortran, Go 1.11+, Java 8+, and Python 3+.

For example: You may have legacy code using Python version 2.7 that is in the source tree but isn’t being used. The tool will scan the code base and point out issues in that particular codebase even though you may not be using that piece of code.  To mitigate, either  remove that folder from the source code or ignore the error pointed by the tool.

  1. I see mention of Ruby and .Net in the Open source tool, but they don’t work on my tool.

Ruby and .Net haven’t been implemented yet, but please consider contributing to it and open an issue requesting support. If you need support then see our CONTRIBUTING file.

Troubleshooting

Errors that you may encounter while building the tool binary:

PyInstaller needs a shared version of libraries.

  1. Python 3.10+ not having shared libraries for use by the PyInstaller tool.

Building Porting Advisor binaries

Pyinstaller failed at building binary and suggesting building Python configure script with --enable-shared on Linux or --enable-framework on macOS

The fix for this is to build your version of Python(3.10+) with the right flags:

./configure --enable-optimizations --enable-shared

If the two flags don’t work together, try doing the build with each flag enabled sequentially.

pyinstaller tool needs python configure script with --enable-shared and enable-optimizations flag

  1. Incorrect Python version (version less than 3.10).If you aren’t on the correct version of Python:

You will get errors similar to the ones here:

Python version on host is 3.7.15 which is less than the recommended version

If you want to run the tool in an EC2 instance on Amazon Linux 2(AL2), then you could try upgrading/installing Python 3.10 as pointed out here.

If you run into any issues, then see our CONTRIBUTING file.

Trying to run Porting Advisor as script will result in Syntax errors on Python version less than 3.10

Conclusion

Porting Advisor for Graviton helps customers quantify the amount of work that is required to port an application. It accelerates your ability to transition to Graviton-based Amazon EC2 instances by reducing the iterative process of identifying and resolving source code and library dependencies.

Resources

To learn how to migrate your workloads to Graviton-based instances, see the AWS Graviton Technical Guide GitHub Repository and AWS Graviton Transition Guide. To get started with Graviton-based Amazon EC2 instances, see the AWS Management Console, AWS Command Line Interface (AWS CLI), and AWS SDKs.

Some other resources include:

Fines as a Security System

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/fines-as-a-security-system.html

Tile has an interesting security solution to make its tracking tags harder to use for stalking:

The Anti-Theft Mode feature will make the devices invisible to Scan and Secure, the company’s in-app feature that lets you know if any nearby Tiles are following you. But to activate the new Anti-Theft Mode, the Tile owner will have to verify their real identity with a government-issued ID, submit a biometric scan that helps root out fake IDs, agree to let Tile share their information with law enforcement and agree to be subject to a $1 million penalty if convicted in a court of law of using Tile for criminal activity. So although it technically makes the device easier for stalkers to use Tiles silently, it makes the penalty of doing so high enough to (at least in theory) deter them from trying.

Interesting theory. But it won’t work against attackers who don’t have any money.

Hulls believes the approach is superior to Apple’s solution with AirTag, which emits a sound and notifies iPhone users that one of the trackers is following them.

My complaint about the technical solutions is that they only work for users of the system. Tile security requires an “in-app feature.” Apple’s AirTag “notifies iPhone users.” What we need is a common standard that is implemented on all smartphones, so that people who don’t use the trackers can be alerted if they are being surveilled by one of them.

Friday Squid Blogging: Thermal Batteries from Squid Proteins

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/friday-squid-blogging-thermal-batteries-from-squid-proteins.html

Researchers are making thermal batteries from “a synthetic material that’s derived from squid ring teeth protein.”

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Defending against AI Lobbyists

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/defending-against-ai-lobbyists.html

When is it time to start worrying about artificial intelligence interfering in our democracy? Maybe when an AI writes a letter to The New York Times opposing the regulation of its own technology.

That happened last month. And because the letter was responding to an essay we wrote, we’re starting to get worried. And while the technology can be regulated, the real solution lies in recognizing that the problem is human actors—and those we can do something about.

Our essay argued that the much heralded launch of the AI chatbot ChatGPT, a system that can generate text realistic enough to appear to be written by a human, poses significant threats to democratic processes. The ability to produce high quality political messaging quickly and at scale, if combined with AI-assisted capabilities to strategically target those messages to policymakers and the public, could become a powerful accelerant of an already sprawling and poorly constrained force in modern democratic life: lobbying.

We speculated that AI-assisted lobbyists could use generative models to write op-eds and regulatory comments supporting a position, identify members of Congress who wield the most influence over pending legislation, use network pattern identification to discover undisclosed or illegal political coordination, or use supervised machine learning to calibrate the optimal contribution needed to sway the vote of a legislative committee member.

These are all examples of what we call AI hacking. Hacks are strategies that follow the rules of a system, but subvert its intent. Currently a human creative process, future AIs could discover, develop, and execute these same strategies.

While some of these activities are the longtime domain of human lobbyists, AI tools applied against the same task would have unfair advantages. They can scale their activity effortlessly across every state in the country—human lobbyists tend to focus on a single state—they may uncover patterns and approaches unintuitive and unrecognizable by human experts, and do so nearly instantaneously with little chance for human decision makers to keep up.

These factors could make AI hacking of the democratic process fundamentally ungovernable. Any policy response to limit the impact of AI hacking on political systems would be critically vulnerable to subversion or control by an AI hacker. If AI hackers achieve unchecked influence over legislative processes, they could dictate the rules of our society: including the rules that govern AI.

We admit that this seemed far fetched when we first wrote about it in 2021. But now that the emanations and policy prescriptions of ChatGPT have been given an audience in the New York Times and innumerable other outlets in recent weeks, it’s getting harder to dismiss.

At least one group of researchers is already testing AI techniques to automatically find and advocate for bills that benefit a particular interest. And one Massachusetts representative used ChatGPT to draft legislation regulating AI.

The AI technology of two years ago seems quaint by the standards of ChatGPT. What will the technology of 2025 seem like if we could glimpse it today? To us there is no question that now is the time to act.

First, let’s dispense with the concepts that won’t work. We cannot solely rely on explicit regulation of AI technology development, distribution, or use. Regulation is essential, but it would be vastly insufficient. The rate of AI technology development, and the speed at which AI hackers might discover damaging strategies, already outpaces policy development, enactment, and enforcement.

Moreover, we cannot rely on detection of AI actors. The latest research suggests that AI models trying to classify text samples as human- or AI-generated have limited precision, and are ill equipped to handle real world scenarios. These reactive, defensive techniques will fail because the rate of advancement of the “offensive” generative AI is so astounding.

Additionally, we risk a dragnet that will exclude masses of human constituents that will use AI to help them express their thoughts, or machine translation tools to help them communicate. If a written opinion or strategy conforms to the intent of a real person, it should not matter if they enlisted the help of an AI (or a human assistant) to write it.

Most importantly, we should avoid the classic trap of societies wrenched by the rapid pace of change: privileging the status quo. Slowing down may seem like the natural response to a threat whose primary attribute is speed. Ideas like increasing requirements for human identity verification, aggressive detection regimes for AI-generated messages, and elongation of the legislative or regulatory process would all play into this fallacy. While each of these solutions may have some value independently, they do nothing to make the already powerful actors less powerful.

Finally, it won’t work to try to starve the beast. Large language models like ChatGPT have a voracious appetite for data. They are trained on past examples of the kinds of content that they will be asked to generate in the future. Similarly, an AI system built to hack political systems will rely on data that documents the workings of those systems, such as messages between constituents and legislators, floor speeches, chamber and committee voting results, contribution records, lobbying relationship disclosures, and drafts of and amendments to legislative text. The steady advancement towards the digitization and publication of this information that many jurisdictions have made is positive. The threat of AI hacking should not dampen or slow progress on transparency in public policymaking.

Okay, so what will help?

First, recognize that the true threats here are malicious human actors. Systems like ChatGPT and our still-hypothetical political-strategy AI are still far from artificial general intelligences. They do not think. They do not have free will. They are just tools directed by people, much like lobbyist for hire. And, like lobbyists, they will be available primarily to the richest individuals, groups, and their interests.

However, we can use the same tools that would be effective in controlling human political influence to curb AI hackers. These tools will be familiar to any follower of the last few decades of U.S. political history.

Campaign finance reforms such as contribution limits, particularly when applied to political action committees of all types as well as to candidate operated campaigns, can reduce the dependence of politicians on contributions from private interests. The unfair advantage of a malicious actor using AI lobbying tools is at least somewhat mitigated if a political target’s entire career is not already focused on cultivating a concentrated set of major donors.

Transparency also helps. We can expand mandatory disclosure of contributions and lobbying relationships, with provisions to prevent the obfuscation of the funding source. Self-interested advocacy should be transparently reported whether or not it was AI-assisted. Meanwhile, we should increase penalties for organizations that benefit from AI-assisted impersonation of constituents in political processes, and set a greater expectation of responsibility to avoid “unknowing” use of these tools on their behalf.

Our most important recommendation is less legal and more cultural. Rather than trying to make it harder for AI to participate in the political process, make it easier for humans to do so.

The best way to fight an AI that can lobby for moneyed interests is to help the little guy lobby for theirs. Promote inclusion and engagement in the political process so that organic constituent communications grow alongside the potential growth of AI-directed communications. Encourage direct contact that generates more-than-digital relationships between constituents and their representatives, which will be an enduring way to privilege human stakeholders. Provide paid leave to allow people to vote as well as to testify before their legislature and participate in local town meetings and other civic functions. Provide childcare and accessible facilities at civic functions so that more community members can participate.

The threat of AI hacking our democracy is legitimate and concerning, but its solutions are consistent with our democratic values. Many of the ideas above are good governance reforms already being pushed and fought over at the federal and state level.

We don’t need to reinvent our democracy to save it from AI. We just need to continue the work of building a just and equitable political system. Hopefully ChatGPT will give us all some impetus to do that work faster.

This essay was written with Nathan Sanders, and appeared on the Belfer Center blog.

ChatGPT Is Ingesting Corporate Secrets

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/chatgpt-is-ingesting-corporate-secrets.html

Interesting:

According to internal Slack messages that were leaked to Insider, an Amazon lawyer told workers that they had “already seen instances” of text generated by ChatGPT that “closely” resembled internal company data.

This issue seems to have come to a head recently because Amazon staffers and other tech workers throughout the industry have begun using ChatGPT as a “coding assistant” of sorts to help them write or improve strings of code, the report notes.

[…]

“This is important because your inputs may be used as training data for a further iteration of ChatGPT,” the lawyer wrote in the Slack messages viewed by Insider, “and we wouldn’t want its output to include or resemble our confidential information.”

Upcoming Speaking Engagements

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2023/02/upcoming-speaking-engagements-27.html

This is a current list of where and when I am scheduled to speak:

The list is maintained on this page.

What Will It Take?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/what-will-it-take.html

What will it take for policy makers to take cybersecurity seriously? Not minimal-change seriously. Not here-and-there seriously. But really seriously. What will it take for policy makers to take cybersecurity seriously enough to enact substantive legislative changes that would address the problems? It’s not enough for the average person to be afraid of cyberattacks. They need to know that there are engineering fixes—and that’s something we can provide.

For decades, I have been waiting for the “big enough” incident that would finally do it. In 2015, Chinese military hackers hacked the Office of Personal Management and made off with the highly personal information of about 22 million Americans who had security clearances. In 2016, the Mirai botnet leveraged millions of Internet-of-Things devices with default admin passwords to launch a denial-of-service attack that disabled major Internet platforms and services in both North America and Europe. In 2017, hackers—years later we learned that it was the Chinese military—hacked the credit bureau Equifax and stole the personal information of 147 million Americans. In recent years, ransomware attacks have knocked hospitals offline, and many articles have been written about Russia inside the U.S. power grid. And last year, the Russian SVR hacked thousands of sensitive networks inside civilian critical infrastructure worldwide in what we’re now calling Sunburst (and used to call SolarWinds).

Those are all major incidents to security people, but think about them from the perspective of the average person. Even the most spectacular failures don’t affect 99.9% of the country. Why should anyone care if the Chinese have his or her credit records? Or if the Russians are stealing data from some government network? Few of us have been directly affected by ransomware, and a temporary Internet outage is just temporary.

Cybersecurity has never been a campaign issue. It isn’t a topic that shows up in political debates. (There was one question in a 2016 Clinton–Trump debate, but the response was predictably unsubstantive.) This just isn’t an issue that most people prioritize, or even have an opinion on.

So, what will it take? Many of my colleagues believe that it will have to be something with extreme emotional intensity—sensational, vivid, salient—that results in large-scale loss of life or property damage. A successful attack that actually poisons a water supply, as someone tried to do in January by raising the levels of lye at a Florida water-treatment plant. (That one was caught early.) Or an attack that disables Internet-connected cars at speed, something that was demonstrated by researchers in 2014. Or an attack on the power grid, similar to what Russia did to the Ukraine in 2015 and 2016. Will it take gas tanks exploding and planes falling out of the sky for the average person to read about the casualties and think “that could have been me”?

Here’s the real problem. For the average nonexpert—and in this category I include every lawmaker—to push for change, they not only need to believe that the present situation is intolerable, they also need to believe that an alternative is possible. Real legislative change requires a belief that the never-ending stream of hacks and attacks is not inevitable, that we can do better. And that will require creating working examples of secure, dependable, resilient systems.

Providing alternatives is how engineers help facilitate social change. We could never have eliminated sales of tungsten-filament household light bulbs if fluorescent and LED replacements hadn’t become available. Reducing the use of fossil fuel for electricity generation requires working wind turbines and cost-effective solar cells.

We need to demonstrate that it’s possible to build systems that can defend themselves against hackers, criminals, and national intelligence agencies; secure Internet-of-Things systems; and systems that can reestablish security after a breach. We need to prove that hacks aren’t inevitable, and that our vulnerability is a choice. Only then can someone decide to choose differently. When people die in a cyberattack and everyone asks “What can be done?” we need to have something to tell them.

We don’t yet have the technology to build a truly safe, secure, and resilient Internet and the computers that connect to it. Yes, we have lots of security technologies. We have older secure systems—anyone still remember Apollo’s DomainOS and MULTICS?—that lost out in a market that didn’t reward security. We have newer research ideas and products that aren’t successful because the market still doesn’t reward security. We have even newer research ideas that won’t be deployed, again, because the market still prefers convenience over security.

What I am proposing is something more holistic, an engineering research task on a par with the Internet itself. The Internet was designed and built to answer this question: Can we build a reliable network out of unreliable parts in an unreliable world? It turned out the answer was yes, and the Internet was the result. I am asking a similar research question: Can we build a secure network out of insecure parts in an insecure world? The answer isn’t obviously yes, but it isn’t obviously no, either.

While any successful demonstration will include many of the security technologies we know and wish would see wider use, it’s much more than that. Creating a secure Internet ecosystem goes beyond old-school engineering to encompass the social sciences. It will include significant economic, institutional, and psychological considerations that just weren’t present in the first few decades of Internet research.

Cybersecurity isn’t going to get better until the economic incentives change, and that’s not going to change until the political incentives change. The political incentives won’t change until there is political liability that comes from voter demands. Those demands aren’t going to be solely the results of insecurity. They will also be the result of believing that there’s a better alternative. It is our task to research, design, build, test, and field that better alternative—even though the market couldn’t care less right now.

This essay originally appeared in the May/June 2021 issue of IEEE Security & Privacy. I forgot to publish it here.

How to create custom health checks for your Amazon EC2 Auto Scaling Fleet

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/how-to-create-custom-health-checks-for-your-amazon-ec2-auto-scaling-fleet/

This blog post is written by Gaurav Verma, Cloud Infrastructure Architect, Professional Services AWS.

Amazon EC2 Auto Scaling helps you maintain application availability and lets you automatically add or remove Amazon Elastic Compute Cloud (Amazon EC2) instances according to the conditions that you define. You can use dynamic and predictive scaling to scale-out and scale-in EC2 instances. Auto Scaling helps to maintain the self-healing Amazon EC2 environment for an application where Auto Scaling can use the status of Amazon EC2 health checks to determine if an instance is faulty and needs replacement. Amazon EC2 Auto Scaling provides three types of health checks, which are discussed below.

EC2 Status check: AWS provides two types of health checks for EC2 instances: System status check and instance status check. System status checks monitor the AWS system on which an instance is running. If the problem is with underlying system, AWS will fix the problem. Instance status check monitors the software and network configuration of an instance. If the instance status check fails, then you can fix the problem by following the steps in the troubleshoot instances with failed status checks documentation.

Elastic Load Balancer Health Check: Auto Scaling groups are generally connected to Elastic Load Balancers (ELB). ELB provides the application-level health check by monitoring the endpoint (a webpage, or a health page in a web application) of an application. ELB health check monitors the application and marks the instance unhealthy if there is no response from an instance in the configured time.

Custom Health Check: You can use custom health checks to mark any instance as unhealthy if the instance fails for the check you define. Custom health checks can be used to implement various user requirements, such as the presence of instance tags added upon completion of a required workflow. The user data script is executed at instance boot time, and it can perform additional investigation into whether or not the user requirements are met before confirming that the instance is ready to accept load. For example, this approach could be used to confirm that the instance was successfully integrated with other parts of a complex application stack.

In some cases, a customer may add multiple checks either in the Amazon EC2 AMI or in the boot sequence to keep the instance secure and compliant. These checks can increase the boot time for the EC2 instance, and they can reboot the EC2 instance multiple times before an instance can be marked as compliant. Therefore, in some cases, an EC2 instance boot period can take forty to fifty minutes or longer.

If an EC2 instance isn’t marked as healthy within a defined time, Auto Scaling will mark an instance unhealthy, even though the instance wasn’t yet ready for evaluation. Custom health checks can help manage these situations. You can write the Amazon EC2 user data script to perform the custom health check and force Auto Scaling to wait until the instance is truly healthy (i.e., functional, secure, and compliant).

This blog describes a method to write a custom health check. We write an Amazon EC2 user data script to perform the custom health check and automate it for future EC2 instances in the Auto Scaling group. This script can wait for an instance to successfully complete the boot process and then mark the instance as healthy.

Prerequisites

You must have an AWS Identity and Access Management (IAM) role for Amazon EC2 with an Auto Scaling policy, which has these two actions allowed for the Auto Scaling group:

autoscaling:CompleteLifecycleAction

autoscaling:RecordLifecycleActionHeartbeat

Furthermore, we use the Amazon EC2 Auto Scaling lifecycle hooks. Lifecycle hooks let you create a solutions that are aware of events in Auto Scaling instance lifecycle, and then perform a custom action on instances when the lifecycle event occurs. As mentioned previously, typically a custom health check is needed when determining the workload readiness of an instance would be longer than the usual boot time for an EC2 instance that Auto Scaling assumes. Therefore, we utilize lifecycle hooks to keep the checks running until the instance is marked healthy.

Create custom health check

Let’s look at an example where an instance can only be marked as healthy if the instance has a tag with the key “Compliance-Check” and value “Successful”. Until this tag is both (a) present and (b) carries the value “Successful”, the instance shouldn’t be marked as “InService”.

  1. Create the Auto Scaling launch template for Amazon EC2 Auto Scaling. Name your Launch template “test”. In the additional configuration for user data, use this shell script as text.

The Following script will install the AWS Command Line Interface (AWS CLI) to interact with the AWS tagging and Auto Scaling APIs. Then, the script will run the while loop until the instance has a tag with the key “Compliance-Check” and value “Successful”. Once the instance has a tag, it will mark the instance as healthy and the instance will move into the “InService” state.

#!/bin/bash
curl "https://awscli.amazonaws.com/awscli-exe-linux-x86_64.zip" -o "awscliv2.zip"
unzip awscliv2.zip
sudo ./aws/install
#get instance id
instance=$(curl http://169.254.169.254/latest/meta-data/instance-id)

#Checking instance status
while true
do
readystatus=$(aws ec2 describe-instances --instance-ids $instance --filters "Name=tag: Compliance-Check,Values= Successful" |grep -i $instance)
if [[ $readystatus = *"InstanceId"* ]]; then
        echo $readystatus >> /home/ec2-user/user-script-output.txt
        aws autoscaling set-instance-health --instance-id $instance --health-status Healthy
        aws autoscaling complete-lifecycle-action --lifecycle-action-result CONTINUE --instance-id $instance --lifecycle-hook-name test --auto-scaling-group-name my-asg
        break 
else
	aws autoscaling set-instance-health --instance-id $instance --health-status Unhealthy
	sleep 5  
fi

done
  1. Create an Amazon EC2 Auto Scaling group using the AWS CLI with the “test” launch template that you just created and a predefined lifecycle hook. First, create a JSON file “config.json” in a system where you will run the AWS command to create the Auto Scaling group.
{
    "AutoScalingGroupName": "my-asg",
    "LaunchTemplate": {"LaunchTemplateId": "lt-1234567890abcde12"} ,
    "MinSize": 2,
    "MaxSize": 4,
    "DesiredCapacity": 2,
    "VPCZoneIdentifier": "subnet-12345678, subnet-90123456",
    "NewInstancesProtectedFromScaleIn": true,
    "LifecycleHookSpecificationList": [
        {
            "LifecycleHookName": "test",
            "LifecycleTransition": "autoscaling:EC2_INSTANCE_LAUNCHING",
            "HeartbeatTimeout": 300,
            "DefaultResult": "ABANDON"
        }
    ],
    "Tags": [
        {
            "ResourceId": "my-asg",
            "ResourceType": "auto-scaling-group",
            "Key": "Compliance-Check",
            "Value": "UnSuccessful",
            "PropagateAtLaunch": true
        }
    ]
}

To create the Auto Scaling group with the AWS CLI, you must run the following command at the same location where you saved the preceding JSON file. Make sure to replace the relevant subnets that you intend to use in the VPCZoneIdentifier.

>> aws autoscaling create-auto-scaling-group –cli-input-json file://config.json

This command will create the Auto Scaling group with a configuration defined in the JSON file. This Auto Scaling group should have two instances and a lifecycle hook called “test” with a 300 second wait period at the time of launch of an instance.

Tests

Now is the time to test the newly-created instances with a custom health check. Instances in Auto Scaling should be in the “Pending:Wait” stage, not the “InService” stage. Instances will be in this stage for approximately five minutes because we have a lifecycle hook time of 300 seconds in the config.json file.

If the workload readiness evaluation takes more than 300 seconds in your environment, then you can increase the lifecycle hook period to as long as 7200 seconds.

Change the tag value for one instance from “UnSuccessful” to “Successful”. If you’ve changed the tag within the five minutes of instances creation, then the instance should be in the “InService” state and marked as healthy.

Change Compliance-Check value from "UnSuccessful" to "Successful".

This test is a simulation of the situation where the health check of an instance depends on the tag values, and the tag values are only updated if the instance passes all of the checks as per the organization standards. Here we change the tag value manually, but in a real use case scenario, this value would be changed by the booting process when instances are marked as compliant.

Another test case could be that an instance should be marked as healthy if it’s added to the configuration management database, but not before that. For these checks, you can use the API with the curl command and look for the desired result. An example to call an API is in the above script, where it calls the AWS API to get the instance ID.

In case your custom health check script needs more than 7200 seconds, you can use this command to increase the lifecycle hook time:

>> aws autoscaling record-lifecycle-action-heartbeat –lifecycle-hook-name <lh_
name> –auto-scaling-group-name <asg_name> –instance-id <instance_id>

This command will give you the extra time equal to the time that you have configured in the life cycle hook.

Cleanup

Once you successfully test the solution, to avoid ongoing charges for resources you created, you should delete the resources.

To delete the Amazon EC2 Auto Scaling group, run the following command:

aws autoscaling delete-auto-scaling-group --auto-scaling-group-name my-asg

To delete the launch template, run the following command:

aws ec2 delete-launch-template --launch-template-id lt-1234567890abcde12

Delete the role and policy as well if you no longer need it.

Conclusion

EC2 Auto Scaling custom health checks are useful when system or instance health is insufficient, and you want instances to be marked as healthy only after additional checks. Typically, because of these different checks, the Amazon EC2 boot period can be longer than usual, and this may impact the scale-out process when an application needs more resources.

You can start by exploring EC2 Auto Scaling warm pools for these environments. You can keep the healthy marked instances in the warm pool in the Stopped stage. Then, these instances can be brought into the main pool at the time of scale-out without spending time on the boot process and lengthy health check. If you enable scale-in protection, then these healthy instances can move back to the warm pool at the time of scale-in rather than being terminated altogether.

Friday Squid Blogging: Squid Is a Blockchain Thingy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/friday-squid-blogging-squid-is-a-blockchain-thingy.html

I had no idea—until I read this incredibly jargon-filled article:

Squid is a cross-chain liquidity and messaging router that swaps across multiple chains and their native DEXs via axlUSDC.

So there.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

A Hacker’s Mind Is Now Published

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/a-hackers-mind-is-now-published.html

Tuesday was the official publication date of A Hacker’s Mind: How the Powerful Bend Society’s Rules, and How to Bend them Back. It broke into the 2000s on the Amazon best-seller list.

Reviews in the New York Times, Cory Doctorow’s blog, Science, and the Associated Press.

I wrote essays related to the book for CNN and John Scalzi’s blog.

Two podcast interviews: Keen On and Lawfare. And a written interview for the Ash Center at the Harvard Kennedy School.

Lots more coming, I believe. Get your copy here.

And—last request—right now there’s one Amazon review, and it’s not a good one. If people here could leave reviews, I would appreciate it.

Scaling an ASG using target tracking with a dynamic SQS target

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/scaling-an-asg-using-target-tracking-with-a-dynamic-sqs-target/

This blog post is written by Wassim Benhallam, Sr Cloud Application Architect AWS WWCO ProServe, and Rajesh Kesaraju, Sr. Specialist Solution Architect, EC2 Flexible Compute.

Scaling an Amazon EC2 Auto Scaling group based on Amazon Simple Queue Service (Amazon SQS) is a commonly used design pattern in decoupled applications. For example, an EC2 Auto Scaling Group can be used as a worker tier to offload the processing of audio files, images, or other files sent to the queue from an upstream tier (e.g., web tier). For latency-sensitive applications, AWS guidance describes a common pattern that allows an Auto Scaling group to scale in response to the backlog of an Amazon SQS queue while accounting for the average message processing duration (MPD) and the application’s desired latency.

This post builds on that guidance to focus on latency-sensitive applications where the MPD varies over time. Specifically, we demonstrate how to dynamically update the target value of the Auto Scaling group’s target tracking policy based on observed changes in the MPD. We also cover the utilization of Amazon EC2 Spot instances, mixed instance policies, and attribute-based instance selection in the Auto Scaling Groups as well as best practice implementation to achieve greater cost savings.

The challenge

The key challenge that this post addresses is applications that fail to honor their acceptable/target latency in situations where the MPD varies over time. Latency refers here to the time required for any queue message to be consumed and fully processed.

Consider the example of a customer using a worker tier to process image files (e.g., resizing, rescaling, or transformation) uploaded by users within a target latency of 100 seconds. The worker tier consists of an Auto Scaling group configured with a target tracking policy. To achieve the target latency mentioned previously, the customer assumes that each image can be processed in one second, and configures the target value of the scaling policy so that the average image backlog per instance is maintained at approximately 100 images.

In the first week, the customer submits 1000 images to the Amazon SQS queue for processing, each of which takes one second of processing time. Therefore, the Auto Scaling group scales to 10 instances, each of which processes 100 images in 100s, thereby honoring the target latency of 100s.

In the second week, the customer submits 1000 slightly larger images for processing. Since an image’s processing duration scales with its size, each image takes two seconds to process. As in the first week, the Auto Scaling group scales to 10 instances, but this time each instance processes 100 images in 200s, which is twice as long as was needed in the first round. As a result, the application fails to process the latter images within its acceptable latency.

Therefore, the challenge is common to any latency-sensitive application where the MPD is subject to change. Applications where the processing duration scales with input data size are particularly vulnerable to this problem. This includes image processing, document processing, computational jobs, and others.

Solution overview

Before we dive into the solution, let’s briefly review the target tracking policy’s scaling metric and its corresponding target value. A target tracking scaling policy works by adjusting the capacity to keep a scaling metric at, or close to, the specified target value. When scaling in response to an Amazon SQS backlog, it’s good practice to use a scaling metric known as the Backlog Per Instance (BPI) and a target value based on the acceptable BPI. These are computed as follows:

BPI equation, Saling metric and target value.

Given the acceptable BPI equation, a longer MPD requires us to use a smaller target value if we are to process these messages in the same acceptable latency, and vice versa. Therefore, the solution we propose here works by monitoring the average MPD over time and dynamically adjusting the target value of the Auto Scaling group’s target tracking policy (acceptable BPI) based on the observed changes in the MPD. This allows the scaling policy to adapt to variations in the average MPD over time, and thus enables the application to honor its acceptable latency.

Solution architecture

To demonstrate how the approach above can be implemented in practice, we put together an example architecture highlighting the services involved (see the following figure). We also provide an automated deployment solution for this architecture using an AWS Serverless Application Model (AWS SAM) template and some Python code (repository link). The repository also includes a README file with detailed instructions that you can follow to deploy the solution. The AWS SAM template deploys several resources, including an autoscaling group, launch template, target tracking scaling policy, an Amazon SQS queue, and a few AWS Lambda functions that serve various functions described as follows.

The Amazon SQS queue is used to accumulate messages intended for processing, while the Auto Scaling group instances are responsible for polling the queue and processing any messages received. To do this, a launch template defines a bootstrap script that allows the group’s instances to download and execute a Python code when first launched. The Python code consumes messages from the Amazon SQS queue and simulates their processing by sleeping for the MPD duration specified in the message body. After processing each message, the instance publishes the MPD as an Amazon CloudWatch metric (see the following figure).

Figure 1: Architecture diagram showing the components deployed by the AWS SAM template. These include an SQS queue, an Auto Scaling group responsible for polling and processing queue messages, a Lambda function that regularly updates the BPI CloudWatch metric, and a “Target Setter” Lambda function that regularly updates the Auto Scaling group’s target tracking scaling policy.

Figure 1: Architecture diagram showing the components deployed by the AWS SAM template.

To enable scaling, the Auto Scaling group is configured with a target tracking scaling policy that specifies BPI as the scaling metric and with an initial target value provided by the user.

The BPI CloudWatch metric is calculated and published by the “Metric-Publisher” Lambda function which is invoked every one minute using an Amazon EventBridge rate expression. To calculate BPI, the Lambda function simply takes the ratio of the number of messages visible in the Amazon SQS queue by the total number of in-service instances in the Auto Scaling group, as shown in equation (2) above.

On the other hand, the scaling policy’s target value is updated by the “Target-Setter” Lambda function, which is invoked every 30 minutes using another EventBridge rate expression. To calculate the new target value, the Lambda function simply takes the ratio of the user-defined acceptable latency value by the current average MPD queried from the corresponding CloudWatch metric, as shown in the previous equation (1).

Finally, to help you quickly test this solution, a Lambda function “Testing Lambda” is also provided and can be used to send messages to the Amazon SQS queue with a processing duration of your choice. This is specified within each message’s body. You can invoke this Lambda function with different MPDs (by modifying the corresponding environment variable) to verify how the Auto Scaling group scales in response. A CloudWatch dashboard is also deployed to enable you to track key scaling metrics through time. These include the number of messages visible in the queue, the number of in-service instances in the Auto Scaling group, the MPD, and BPI vs acceptable BPI.

Solution testing

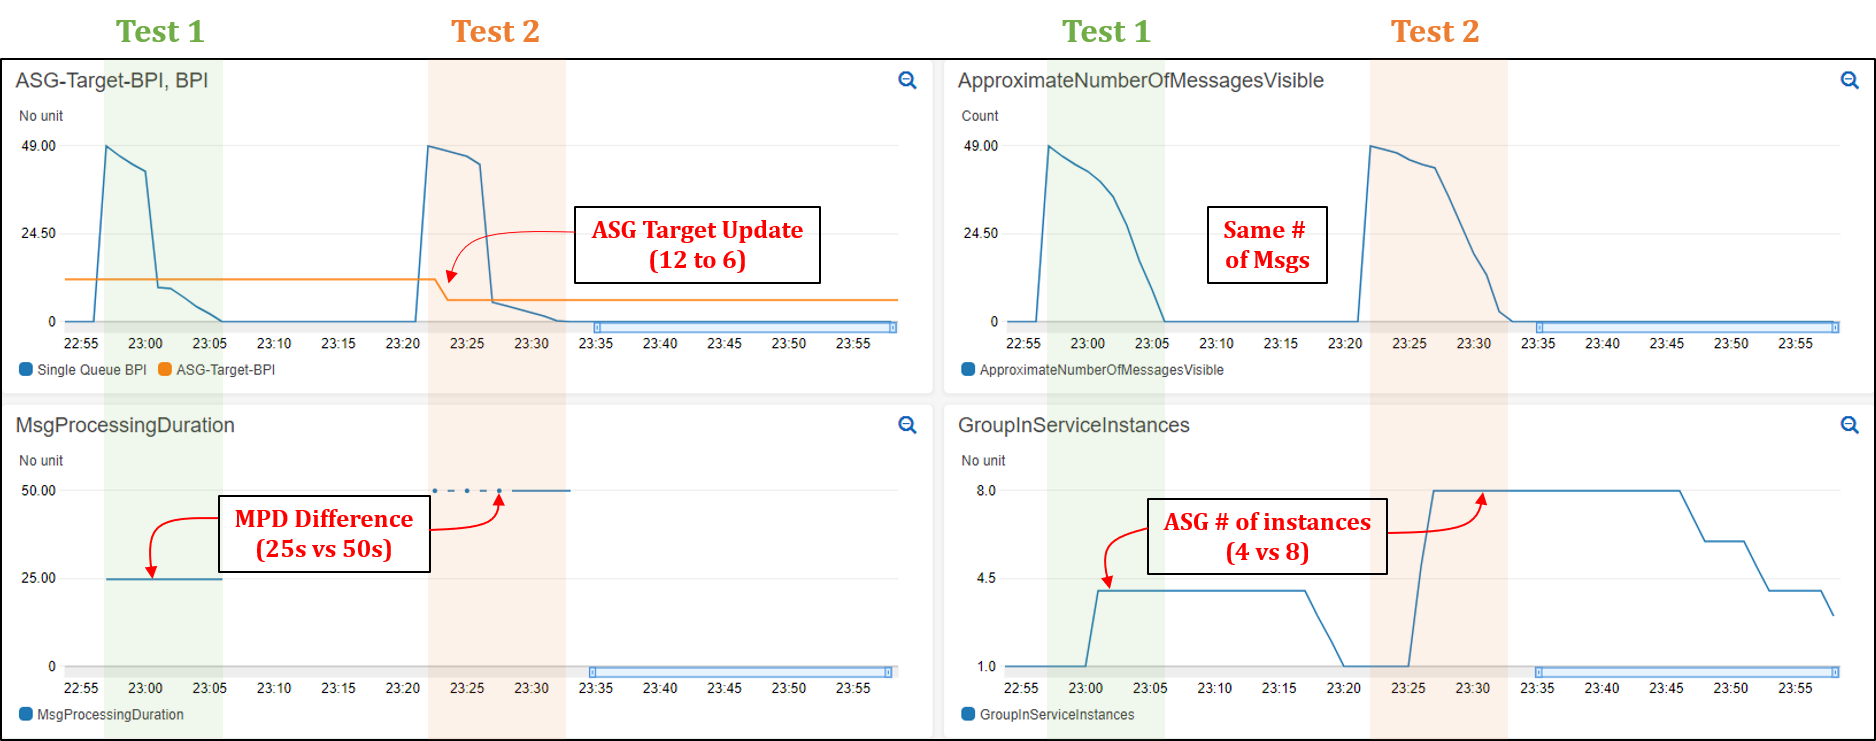
To demonstrate the solution in action and its impact on application latency, we conducted two tests that you can reproduce by following the instructions described in the “Testing” section of the repository’s README file (repository link). In both tests, we assume a hypothetical application with a target latency of 300s. We also modified the invocation frequency of the “Target Setter” Lambda function to one minute to quickly assess the impact of target value changes. In both tests, we submit 50 messages to the Amazon SQS queue through the provided helper lambda. An MPD of 25s and 50s was used for the first and second test, respectively. The provided CloudWatch dashboard shows that the ASG scales to a total of four instances in the first test, and eight instances in the second (see the following figure). See README file for a detailed description of how various metrics evolve over time.

Comparison of Tests 1 and 2

Since Test 2 messages take twice as long to process, the Auto Scaling group launched twice as many instances to attempt to process all of the messages in the same amount of time as Test 1 (latency). The following figure shows that the total time to process all 50 messages in Test 1 was 9 mins vs 10 mins in Test 2. In contrast, if we were to use a static/fixed acceptable BPI of 12, then a total of four instances would have been operational in Test 2, thereby requiring double the time of Test 1 (~20 minutes) to process all of the messages. This demonstrates the value of using a dynamic scaling target when processing messages from Amazon SQS queues, especially in circumstances where the MPD is prone to vary with time.

Figure 2: CloudWatch dashboard showing Auto Scaling group scaling test results (Test 1 and 2). Although Test 2 messages require double the MPD of Test 1 messages, the Auto Scaling group processed Test 2 messages in the same amount of time as Test 1 by launching twice as many instances.

Figure 2: CloudWatch dashboard showing Auto Scaling group scaling test results (Test 1 and 2).

Recommended best practices for Auto Scaling groups

This section highlights a few key best practices that we recommend adopting when deploying and working with Auto Scaling groups.

Reducing cost using EC2 Spot instances

Amazon SQS helps build loosely coupled application architectures, while providing reliable asynchronous communication between the various layers/components of an application. If a worker node fails to process a message within the Amazon SQS message visibility time-out, then the message is returned to the queue and another worker node can pick up and process that message. This makes Amazon SQS-backed applications fault-tolerant by design and thus a great fit for EC2 Spot instances. EC2 spot instances are spare compute capacity in the AWS cloud that is available to you at steep discounts as compared to On-Demand prices.

Maximizing capacity using attribute-based instance selection

With the recently released attribute-based instance selection feature, you can define infrastructure requirements based on application needs such as vCPU, RAM, and processor family (e.g., x86, ARM). This removes the need to define specific instances in your Auto Scaling group configuration, and it eliminates the burden of identifying the correct instance families and sizes. In addition, newly released instance types will be automatically considered if they fit your requirements. Attribute-based instance selection lets you tap into hundreds of different EC2 instance pools, which increases the chance of getting EC2 (Spot/On-demand) instances. When using attribute-based instance selection with the capacity optimized allocation strategy, Amazon EC2 allocates instances from deeper Spot capacity pools, thereby further reducing the chance of Spot interruption.

The following sample configuration creates an Auto Scaling group with attribute-based instance selection:

AutoScalingGroupName: 'my-asg' # [REQUIRED] 
MixedInstancesPolicy:
  LaunchTemplate:
    LaunchTemplateSpecification:
      LaunchTemplateId: 'lt-0537239d9aef10a77'
    Overrides:
    - InstanceRequirements:
        VCpuCount: # [REQUIRED] 
          Min: 2
          Max: 4
        MemoryMiB: # [REQUIRED] 
          Min: 2048
  InstancesDistribution:
    SpotAllocationStrategy: 'capacity-optimized'
MinSize: 0 # [REQUIRED] 
MaxSize: 100 # [REQUIRED] 
DesiredCapacity: 4
VPCZoneIdentifier: 'subnet-e76a128a,subnet-e66a128b,subnet-e16a128c'

Conclusion

As can be seen from the test results, this approach demonstrates how an Auto Scaling group can honor a user-provided acceptable latency constraint while accomodating variations in the MPD over time. This is possible because the average MPD is monitored and regularly updated as a CloudWatch metric. In turn, this is continously used to update the target value of the group’s target tracking policy. Moreover, we have covered additional Auto Scaling group best practices suitable for this use case, including the use of Spot instances to reduce costs and attribute-based instance selection to simplify the selection of relevant instance types.

For more information on scaling options for Auto Scaling groups, visit the Amazon EC2 Auto Scaling documentation page and the SQS-based scaling guide.

How to choose between CoIP and Direct VPC routing modes on AWS Outposts rack

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/how-to-choose-between-coip-and-direct-vpc-routing-modes-on-aws-outposts-rack/

This blog post is written by Sumit Menaria, Senior Hybrid Solutions Architect AWS WWSO Core Services.

AWS Outposts Rack is a fully-managed service that extends AWS infrastructure, services, APIs, and tools to customer premises. By providing local access to AWS managed infrastructure and services, Outposts rack enables customers to build and run applications on premises using the same programming interfaces as in AWS Regions, while using local compute and storage resources for low latency, local data processing, and data residency needs.

There are various data sources on premises that you might want to connect from your Outpost. These sources can include field devices, on-premises databases, mainframes, storage arrays, or end users. Each Outpost supports a single Local Gateway (LGW) construct, which enables connectivity from your Outpost subnets to an on-premises network. Note that this post is specific to Outposts racks and a different method of local communication is used for AWS Outposts servers.

Two different options for facilitating communication between your Outpost based resources and on-premises network: Direct VPC routing and customer-owned IP pool. Both of these are mutually exclusive options, and routing works differently based on your choice of the mode. The two modes are the attributes of the LGW route table that your Outpost subnets’ VPC is associated with, which specifies the communication mode for the Outpost subnets.

Direct VPC routing mode

Direct VPC routing uses the private IP address of the instances in the VPC CIDR block to facilitate communication with your on-premises network. These addresses are advertised to your on-premises network with Border Gateway Protocol (BGP). Advertisement via BGP is only for the private IP addresses that belong to the subnets on your Outpost and have a route pointing to the LGW via the subnet’s route table. This type of routing is the default mode for Outposts Rack. In this mode, the LGW doesn’t perform Network Address Translation (NAT) for instances. Furthermore, you don’t have to assign an Elastic IP address to your Amazon Elastic Compute Cloud (Amazon EC2) instance from a (CoIP) to enable communication with your on-premises resources.

A diagram showing how an EC2 instance on an Outpost communicates with on-premises network using direct VPC routing mode

In this diagram, when the instance Y wants to communicate with an on-premises server, it traverses the LGW and can talk to the on-premises server using its source address (10.0.1.11) in the Subnet CIDR range (10.0.1.0/24) that is advertised over BGP from the LGW to the Customer Network Device. Similarly when the on-premises server wants to initiate communication with the Outpost based EC2 instance, it uses the instance’s private IP address (10.0.1.11) as the destination IP address to set up the connection.

CoIP mode

Utilizing CoIP mode means that you must provide a separate IP address range from your on-premises IP space for AWS to create an address pool, known as a CoIP. With CoIP, when an Outpost based resources, such as EC2 instances, Application Load Balancer (ALB), or Amazon Relational Database Service (Amazon RDS) instances, need to communicate to your on-premises network, the Local Gateway will perform 1:1 NAT from the resource’s private IP address from the Outpost subnet range to an IP address from the CoIP pool. The subnet-to-CoIP address mapping is done by assigning an Elastic IP (EIP) from the CoIP address range allocated for resources such as EC2 instances. To enable the communication with the CoIP pool from the on-premises network, and then the LGW advertises the CoIP pool through BGP over its peering with the Customer Network Device.

A diagram showing how an EC2 instance on an Outpost communicates with on-premises network using CoIP mode

In this diagram, when the instance Y wants to talk to an on-premises server, the traffic traverses the LGW and the source IP address (10.0.1.11) of the instance gets translated to an IP address (192.168.0.11) in the CoIP range that is associated with the instance. Similarly, when the on-premises server initiates the communication, the request will be sent with the CoIP address (192.168.0.11) of the instance as the destination IP address. This will be changed to the instance’s private IP address (10.0.1.11) via NAT at the LGW. The CoIP pool (192.168.0.0/26) is advertised via BGP to the Customer Network Device to provide the route to the on-premises environment for reaching the Outpost based resources.

When to choose CoIP routing mode

CoIP is particularly useful when you want to isolate your Outpost based workloads from the on-premises infrastructure and only need specific resources on the Outpost to be able to communicate to the on-premises infrastructure. This is useful in situations where large enterprise networks have hundreds of IP pools allocated and there is a high chance of overlap between IP addresses allocated to Outpost based VPCs/Subnets and those allocated to on-premises infrastructure. Furthermore, CoIP can act as another layer of security, as you may choose to allocate the CoIP addresses to only the resources which must communicate with the on-premises network. Then you can allocate for the rest of them using the subnet private IP address range for communication within the Outpost or Region based resources.

This means that you don’t need to have the number of IPs in the CoIP pool be equal to the number of resources on your Outpost. For example, you may choose to configure a /26 CoIP range and a /22 pool for subnets to meet your workload requirements.

CoIP mode can also be useful when using an external ALB on Outpost and you want to make it routable through the local internet connectivity. By using a smaller internet routable CoIP address range assignment for your external ALB, you can route traffic to the ALB on the Outpost without needing to traverse through the internet gateway (IGW) in the parent Region.

When to choose Direct VPC routing mode

You can choose Direct VPC routing if you don’t want the operational overhead of managing the additional IP pools for NAT between your Outpost based resources and on-premises network. There are also few applications which may not work well if there is an NAT of IPs between the two endpoints communicating with each other. Some examples you may see are Active Directory communication with on-premises based servers, or iSCSI mount of your instances as an additional storage to on-premises Storage Area Network (SAN). These applications may not work or may need additional tuning if they encounter NATed IP addresses between an Outpost based client on an EC2 instance and on-premises based server for a two-way communication.

When Direct VPC routing mode is used, multiple VPCs can be associated to an Outpost LGW route table, and the Outpost subnets with the LGW as the route target, are automatically advertised to the on-premises network through BGP. Therefore, you must make sure that appropriate IP planning is in place to avoid any overlap of the Outpost VPC/Subnet IP range with the on-premises IP range, as they are directly advertised from LGW toward the Customer Network Device. Having overlapping IP subnets in your network can lead to undesired effects on your application connectivity and you must pay special attention when allocating IP pools for your on-premises and Outpost based VPC address space. You can use Amazon VPC IP Address Manager (IPAM) to plan the IP space of your VPCs and CoIP pools, as well as add on-premises based IP Pools using manual allocation.

Conclusion

You can select either Direct VPC routing or CoIP mode for routing through an Outpost Local Gateway. Since this selection affects the routing for all of the subnets on your Outpost associated with the LGW route table, it should be selected based on your workload requirements and existing IP infrastructure planning. You can also change the LGW route table mode at a later stage. However, that involves network disruption and the creation of a new LGW route table. To learn more about Outposts Racks routing, visit the LGW Route table documentation.

Hacking the Tax Code

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/hacking-the-tax-code.html

The tax code isn’t software. It doesn’t run on a computer. But it’s still code. It’s a series of algorithms that takes an input—financial information for the year—and produces an output: the amount of tax owed. It’s incredibly complex code; there are a bazillion details and exceptions and special cases. It consists of government laws, rulings from the tax authorities, judicial decisions, and legal opinions.

Like computer code, the tax code has bugs. They might be mistakes in how the tax laws were written. They might be mistakes in how the tax code is interpreted, oversights in how parts of the law were conceived, or unintended omissions of some sort or another. They might arise from the exponentially huge number of ways different parts of the tax code interact.

A recent example comes from the 2017 Tax Cuts and Jobs Act. That law was drafted in both haste and secret, and quickly passed without any time for review—or even proofreading. One of the things in it was a typo that accidentally categorized military death benefits as earned income. The practical effect of that mistake is that surviving family members were hit with surprise tax bills of US$10,000 or more.

That’s a bug, but not a vulnerability. An example of a vulnerability is the “Double Irish with a Dutch Sandwich.” It arises from the interactions of tax laws in multiple countries, and it’s how companies like Google and Apple have avoided paying U.S. taxes despite being U.S. companies. Estimates are that U.S. companies avoided paying nearly US$200 billion in taxes in 2017 alone.

In the tax world, vulnerabilities are called loopholes. Exploits are called tax avoidance strategies. And there are thousands of black-hat researchers who examine every line of the tax code looking for exploitable vulnerabilities—tax attorneys and tax accountants.

Some vulnerabilities are deliberately created. Lobbyists are constantly trying to insert this or that provision into the tax code that benefits their clients financially. That same 2017 U.S. tax law included a special tax break for oil and gas investment partnerships, a special exemption that ensures that fewer than 1 in 1,000 estates will have to pay estate tax, and language specifically expanding a pass-through loophole that industry uses to incorporate companies offshore and avoid U.S. taxes. That’s not hacking the tax code. It’s hacking the processes that create them: the legislative process that creates tax law.

We know the processes to use to fix vulnerabilities in computer code. Before the code is finished, we can employ some sort of secure development processes, with automatic bug-finding tools and maybe source code audits. After the code is deployed, we might rely on vulnerability finding by the security community, perhaps bug bounties—and most of all, quick patching when vulnerabilities are discovered.

What does it mean to “patch” the tax code? Passing any tax legislation is a big deal, especially in the United States where the issue is so partisan and contentious. (That 2017 earned income tax bug for military families hasn’t yet been fixed. And that’s an easy one; everyone acknowledges it was a mistake.) We don’t have the ability to patch tax code with anywhere near the same agility that we have to patch software.

We can patch some vulnerabilities, though. The other way tax code is modified is by IRS and judicial rulings. The 2017 tax law capped income tax deductions for property taxes. This provision didn’t come into force in 2018, so someone came up with the clever hack to prepay 2018 property taxes in 2017. Just before the end of the year, the IRS ruled about when that was legal and when it wasn’t. Short answer: most of the time, it wasn’t.

There’s another option: that the vulnerability isn’t patched and isn’t explicitly approved, and slowly becomes part of the normal way of doing things. Lots of tax loopholes end up like this. Sometimes they’re even given retroactive legality by the IRS or Congress after a constituency and lobbying effort gets behind them. This process is how systems evolve. A hack subverts the intent of a system. Whatever governing system has jurisdiction either blocks the hack or allows it—or does nothing and the hack becomes the new normal.

Here’s my question: what happens when artificial intelligence and machine learning (ML) gets hold of this problem? We already have ML systems that find software vulnerabilities. What happens when you feed a ML system the entire U.S. tax code and tell it to figure out all of the ways to minimize the amount of tax owed? Or, in the case of a multinational corporation, to feed it the entire planet’s tax codes? What sort of vulnerabilities would it find? And how many? Dozens or millions?

In 2015, Volkswagen was caught cheating on emissions control tests. It didn’t forge test results; it got the cars’ computers to cheat for them. Engineers programmed the software in the car’s onboard computer to detect when the car was undergoing an emissions test. The computer then activated the car’s emissions-curbing systems, but only for the duration of the test. The result was that the cars had much better performance on the road at the cost of producing more pollution.

ML will result in lots of hacks like this. They’ll be more subtle. They’ll be even harder to discover. It’s because of the way ML systems optimize themselves, and because their specific optimizations can be impossible for us humans to understand. Their human programmers won’t even know what’s going on.

Any good ML system will naturally find and exploit hacks. This is because their only constraints are the rules of the system. If there are problems, inconsistencies, or loopholes in the rules, and if those properties lead to a “better” solution as defined by the program, then those systems will find them. The challenge is that you have to define the system’s goals completely and precisely, and that that’s impossible.

The tax code can be hacked. Financial markets regulations can be hacked. The market economy, democracy itself, and our cognitive systems can all be hacked. Tasking a ML system to find new hacks against any of these is still science fiction, but it’s not stupid science fiction. And ML will drastically change how we need to think about policy, law, and government. Now’s the time to figure out how.

This essay originally appeared in the September/October 2020 issue of IEEE Security & Privacy. I wrote it when I started writing my latest book, but never published it here.

Mary Queen of Scots Letters Decrypted

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/mary-queen-of-scots-letters-decrypted.html

This is a neat piece of historical research.

The team of computer scientist George Lasry, pianist Norbert Biermann and astrophysicist Satoshi Tomokiyo—all keen cryptographers—initially thought the batch of encoded documents related to Italy, because that was how they were filed at the Bibliothèque Nationale de France.

However, they quickly realised the letters were in French. Many verb and adjectival forms being feminine, regular mention of captivity, and recurring names—such as Walsingham—all put them on the trail of Mary. Sir Francis Walsingham was Queen Elizabeth’s spymaster.

The code was a simple replacement system in which symbols stand either for letters, or for common words and names. But it would still have taken centuries to crunch all the possibilities, so the team used an algorithm that homed in on likely solutions.

Academic paper.

EDITED TO ADD (2/13): More news.

Implementing architectural patterns with Amazon EventBridge Pipes

Post Syndicated from David Boyne original https://aws.amazon.com/blogs/compute/implementing-architectural-patterns-with-amazon-eventbridge-pipes/

This post is written by Dominik Richter (Solutions Architect)

Architectural patterns help you solve recurring challenges in software design. They are blueprints that have been used and tested many times. When you design distributed applications, enterprise integration patterns (EIP) help you integrate distributed components. For example, they describe how to integrate third-party services into your existing applications. But patterns are technology agnostic. They do not provide any guidance on how to implement them.

This post shows you how to use Amazon EventBridge Pipes to implement four common enterprise integration patterns (EIP) on AWS. This helps you to simplify your architectures. Pipes is a feature of Amazon EventBridge to connect your AWS resources. Using Pipes can reduce the complexity of your integrations. It can also reduce the amount of code you have to write and maintain.

Content filter pattern

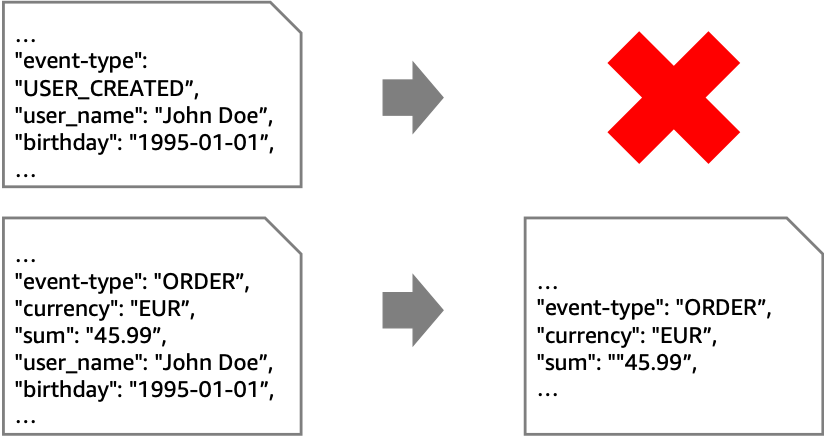
The content filter pattern removes unwanted content from a message before forwarding it to a downstream system. Use cases for this pattern include reducing storage costs by removing unnecessary data or removing personally identifiable information (PII) for compliance purposes.

In the following example, the goal is to retain only non-PII data from “ORDER”-events. To achieve this, you must remove all events that aren’t “ORDER” events. In addition, you must remove any field in the “ORDER” events that contain PII.

While you can use this pattern with various sources and targets, the following architecture shows this pattern with Amazon Kinesis. EventBridge Pipes filtering discards unwanted events. EventBridge Pipes input transformers remove PII data from events that are forwarded to the second stream with longer retention.

Instead of using Pipes, you could connect the streams using an AWS Lambda function. This requires you to write and maintain code to read from and write to Kinesis. However, Pipes may be more cost effective than using a Lambda function.

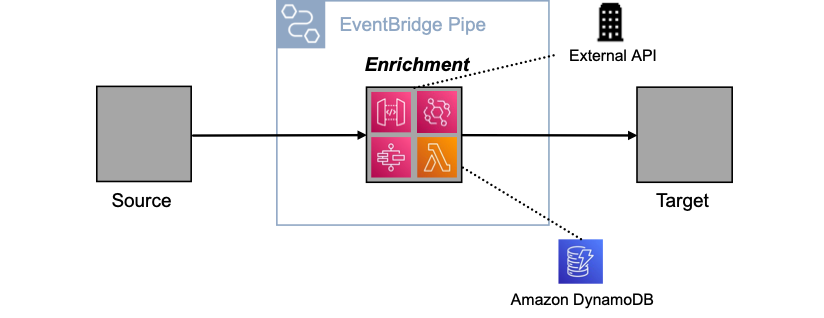
Some situations require an enrichment function. For example, if your goal is to mask an attribute without removing it entirely. For example, you could replace the attribute “birthday” with an “age_group”-attribute.

In this case, if you use Pipes for integration, the Lambda function contains only your business logic. On the other hand, if you use Lambda for both integration and business logic, you do not pay for Pipes. At the same time, you add complexity to your Lambda function, which now contains integration code. This can increase its execution time and cost. Therefore, your priorities determine the best option and you should compare both approaches to make a decision.

To implement Pipes using the AWS Cloud Development Kit (AWS CDK), use the following source code. The full source code for all of the patterns that are described in this blog post can be found in the AWS samples GitHub repo.

const filterPipe = new pipes.CfnPipe(this, 'FilterPipe', {
  roleArn: pipeRole.roleArn,
  source: sourceStream.streamArn,
  target: targetStream.streamArn,
  sourceParameters: { filterCriteria: { filters: [{ pattern: '{"data" : {"event_type" : ["ORDER"] }}' }] }, kinesisStreamParameters: { startingPosition: 'LATEST' } },
  targetParameters: { inputTemplate: '{"event_type": <$.data.event_type>, "currency": <$.data.currency>, "sum": <$.data.sum>}', kinesisStreamParameters: { partitionKey: 'event_type' } },
});

To allow access to source and target, you must assign the correct permissions:

const pipeRole = new iam.Role(this, 'FilterPipeRole', { assumedBy: new iam.ServicePrincipal('pipes.amazonaws.com') });

sourceStream.grantRead(pipeRole);
targetStream.grantWrite(pipeRole);

Message translator pattern

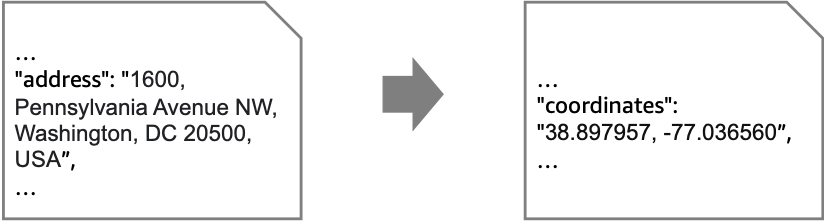
In an event-driven architecture, event producers and consumers are independent of each other. Therefore, they may exchange events of different formats. To enable communication, the events must be translated. This is known as the message translator pattern. For example, an event may contain an address, but the consumer expects coordinates.

If a computation is required to translate messages, use the enrichment step. The following architecture diagram shows how to accomplish this enrichment via API destinations. In the example, you can call an existing geocoding service to resolve addresses to coordinates.

There may be cases where the translation is purely syntactical. For example, a field may have a different name or structure.

You can achieve these translations without enrichment by using input transformers.

Here is the source code for the pipe, including the role with the correct permissions:

const pipeRole = new iam.Role(this, 'MessageTranslatorRole', { assumedBy: new iam.ServicePrincipal('pipes.amazonaws.com'), inlinePolicies: { invokeApiDestinationPolicy } });

sourceQueue.grantConsumeMessages(pipeRole);
targetStepFunctionsWorkflow.grantStartExecution(pipeRole);

const messageTranslatorPipe = new pipes.CfnPipe(this, 'MessageTranslatorPipe', {
  roleArn: pipeRole.roleArn,
  source: sourceQueue.queueArn,
  target: targetStepFunctionsWorkflow.stateMachineArn,
  enrichment: enrichmentDestination.apiDestinationArn,
  sourceParameters: { sqsQueueParameters: { batchSize: 1 } },
});

Normalizer pattern

The normalizer pattern is similar to the message translator but there are different source components with different formats for events. The normalizer pattern routes each event type through its specific message translator so that downstream systems process messages with a consistent structure.

The example shows a system where different source systems store the name property differently. To process the messages differently based on their source, use an AWS Step Functions workflow. You can separate by event type and then have individual paths perform the unifying process. This diagram visualizes that you can call a Lambda function if needed. However, in basic cases like the preceding “name” example, you can modify the events using Amazon States Language (ASL).

In the example, you unify the events using Step Functions before putting them on your event bus. As is often the case with architectural choices, there are alternatives. Another approach is to introduce separate queues for each source system, connected by its own pipe containing only its unification actions.

This is the source code for the normalizer pattern using a Step Functions workflow as enrichment:

const pipeRole = new iam.Role(this, 'NormalizerRole', { assumedBy: new iam.ServicePrincipal('pipes.amazonaws.com') });

sourceQueue.grantConsumeMessages(pipeRole);
enrichmentWorkflow.grantStartSyncExecution(pipeRole);
normalizerTargetBus.grantPutEventsTo(pipeRole);

const normalizerPipe = new pipes.CfnPipe(this, 'NormalizerPipe', {
  roleArn: pipeRole.roleArn,
  source: sourceQueue.queueArn,
  target: normalizerTargetBus.eventBusArn,
  enrichment: enrichmentWorkflow.stateMachineArn,
  sourceParameters: { sqsQueueParameters: { batchSize: 1 } },
});

Claim check pattern

To reduce the size of the events in your event-driven application, you can temporarily remove attributes. This approach is known as the claim check pattern. You split a message into a reference (“claim check”) and the associated payload. Then, you store the payload in external storage and add only the claim check to events. When you process events, you retrieve relevant parts of the payload using the claim check. For example, you can retrieve a user’s name and birthday based on their userID.

The claim check pattern has two parts. First, when an event is received, you split it and store the payload elsewhere. Second, when the event is processed, you retrieve the relevant information. You can implement both aspects with a pipe.

In the first pipe, you use the enrichment to split the event, in the second to retrieve the payload. Below are several enrichment options, such as using an external API via API Destinations, or using Amazon DynamoDB via Lambda. Other enrichment options are Amazon API Gateway and Step Functions.

Using a pipe to split and retrieve messages has three advantages. First, you keep events concise as they move through the system. Second, you ensure that the event contains all relevant information when it is processed. Third, you encapsulate the complexity of splitting and retrieving within the pipe.

The following code implements a pipe for the claim check pattern using the CDK:

const pipeRole = new iam.Role(this, 'ClaimCheckRole', { assumedBy: new iam.ServicePrincipal('pipes.amazonaws.com') });

claimCheckLambda.grantInvoke(pipeRole);
sourceQueue.grantConsumeMessages(pipeRole);
targetWorkflow.grantStartExecution(pipeRole);

const claimCheckPipe = new pipes.CfnPipe(this, 'ClaimCheckPipe', {
  roleArn: pipeRole.roleArn,
  source: sourceQueue.queueArn,
  target: targetWorkflow.stateMachineArn,
  enrichment: claimCheckLambda.functionArn,
  sourceParameters: { sqsQueueParameters: { batchSize: 1 } },
  targetParameters: { stepFunctionStateMachineParameters: { invocationType: 'FIRE_AND_FORGET' } },
});

Conclusion

This blog post shows how you can implement four enterprise integration patterns with Amazon EventBridge Pipes. In many cases, this reduces the amount of code you have to write and maintain. It can also simplify your architectures and, in some scenarios, reduce costs.

You can find the source code for all the patterns on the AWS samples GitHub repo.

For more serverless learning resources, visit Serverless Land. To find more patterns, go directly to the Serverless Patterns Collection.

SolarWinds and Market Incentives

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/solarwinds-and-market-incentives.html

In early 2021, IEEE Security and Privacy asked a number of board members for brief perspectives on the SolarWinds incident while it was still breaking news. This was my response.

The penetration of government and corporate networks worldwide is the result of inadequate cyberdefenses across the board. The lessons are many, but I want to focus on one important one we’ve learned: the software that’s managing our critical networks isn’t secure, and that’s because the market doesn’t reward that security.

SolarWinds is a perfect example. The company was the initial infection vector for much of the operation. Its trusted position inside so many critical networks made it a perfect target for a supply-chain attack, and its shoddy security practices made it an easy target.

Why did SolarWinds have such bad security? The answer is because it was more profitable. The company is owned by Thoma Bravo partners, a private-equity firm known for radical cost-cutting in the name of short-term profit. Under CEO Kevin Thompson, the company underspent on security even as it outsourced software development. The New York Times reports that the company’s cybersecurity advisor quit after his “basic recommendations were ignored.” In a very real sense, SolarWinds profited because it secretly shifted a whole bunch of risk to its customers: the US government, IT companies, and others.

This problem isn’t new, and, while it’s exacerbated by the private-equity funding model, it’s not unique to it. In general, the market doesn’t reward safety and security—especially when the effects of ignoring those things are long term and diffuse. The market rewards short-term profits at the expense of safety and security. (Watch and see whether SolarWinds suffers any long-term effects from this hack, or whether Thoma Bravo’s bet that it could profit by selling an insecure product was a good one.)

The solution here is twofold. The first is to improve government software procurement. Software is now critical to national security. Any system of procuring that software needs to evaluate the security of the software and the security practices of the company, in detail, to ensure that they are sufficient to meet the security needs of the network they’re being installed in. If these evaluations are made public, along with the list of companies that meet them, all network buyers can benefit from them. It’s a win for everybody.

But that isn’t enough; we need a second part. The only way to force companies to provide safety and security features for customers is through regulation. This is true whether we want seat belts in our cars, basic food safety at our restaurants, pajamas that don’t catch on fire, or home routers that aren’t vulnerable to cyberattack. The government needs to set minimum security standards for software that’s used in critical network applications, just as it sets software standards for avionics.

Without these two measures, it’s just too easy for companies to act like SolarWinds: save money by skimping on safety and security and hope for the best in the long term. That’s the rational thing for companies to do in an unregulated market, and the only way to change that is to change the economic incentives.

This essay originally appeared in the March/April 2021 issue of IEEE Security & Privacy.” I forgot to publish it here.