Tag Archives: Uncategorized

A Taxonomy of Access Control

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/08/a-taxonomy-of-access-control.html

My personal definition of a brilliant idea is one that is immediately obvious once it’s explained, but no one has thought of it before. I can’t believe that no one has described this taxonomy of access control before Ittay Eyal laid it out in this paper. The paper is about cryptocurrency wallet design, but the ideas are more general. Ittay points out that a key—or an account, or anything similar—can be in one of four states:

safe Only the user has access,
loss No one has access,
leak Both the user and the adversary have access, or
theft Only the adversary has access.

Once you know these states, you can assign probabilities of transitioning from one state to another (someone hacks your account and locks you out, you forgot your own password, etc.) and then build optimal security and reliability to deal with it. It’s a truly elegant way of conceptualizing the problem.

How to prepare your application to scale reliably with Amazon EC2

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/how-to-prepare-your-application-to-scale-reliably-with-amazon-ec2/

This blog post is written by, Gabriele Postorino, Senior Technical Account Manager, and Giorgio Bonfiglio, Principal Technical Account Manager

In this post, we’ll discuss how you can prepare for planned and unplanned scaling events with

Most of the challenges related to horizontal scaling can be mitigated by optimizing the architectural implementation and applying improvements in operational processes.

In the following sections, we’ll explore this in depth. Recommendations can be applied partially or fully – they come with different complexities, and each one will help you reduce the risk of facing insufficient capacity errors or scaling delays, as well as deliver enhancements in areas such as fault tolerance, elasticity, and cost optimization.

Architectural best practices

Instance capacity can be regarded as being divided into “pools” defined by AZ (such as us-east-1a), instance type (for example m5.xlarge), and tenancy. Combining the following two guidelines will widen the capacity pools available to scale out your fleets of instances. This will help you reduce costs, transparently recover from failures, and increase your application scalability.

Instance flexibility

Whether you’re migrating a new workload to the cloud, or tuning an existing workload, you’ll likely evaluate which compute configuration options are available and determine the right configuration for your application.

If your workload is already running on EC2 instances, you might already be aware of the instance type that it runs best on. Let’s say that your application is RAM intensive, and you found that r6i.4xlarge instances are best suited for it.

However, relying on a single instance type might result in artificially limiting your ability to scale compute resources for your workload when needed. It’s always a good idea to explore how your workload behaves when running on other instance types: you might find that your application can serve double the number of requests served by one r6i.4xlarge instance when using one r6i.8xlarge instance or four r6i.2xlarge instances.

Furthermore, there’s no reason to limit your options to a single instance family, generation, or processor type. For example, m6a.8xlarge instances offer the same amount of RAM of r6i.4xlarge and might be used to run your application if needed.

Amazon EC2 Auto Scaling helps you make sure that you have the right number of EC2 instances available to handle the load for your application.

Auto Scaling groups can be configured to respond to scaling events by selecting the type of instance to launch among a list of instance types. You can statically populate the list in advance, as in the following screenshot,

The Instance type requirements section of the Auto Scaling Wizard instance launch options step is shown with the option “Manually add instance types” selected.

or dynamically define it by a set of instance attributes as shown in the subsequent screenshot:

The Instance type requirements section of the Auto Scaling Wizard instance launch options step is shown with the option “Specify instance attribute” selected.

For example, by setting the requirements to a minimum of 8 vCPUs, 64GiB of Memory, and a RAM/CPU ratio of 8 (just like r6i.2xlarge instances), up to 73 instance types can be included in the list of suitable instances. They will be selected for launch starting from the lowest priced instance types. If the request can’t be fulfilled in full by the lowest priced instance type, then additional instances will be launched from the second lowest instance type pool, and so on.

Instance distribution

Each AWS Region consists of multiple, isolated Availability Zones (AZ), interconnected with high-bandwidth, low-latency networking. Spreading a workload across AZs is a well-established resiliency best practice. It will make sure that your end users aren’t impacted in the case of a single AZ, data center, or rack failures, as each AZ has its own distinct instance capacity pools that you can leverage to scale your application fleets.

EC2 Auto Scaling can manage the optimal distribution of EC2 instances in a group across all AZs in a Region automatically, as well as deal with temporary failures transparently. To do so, it must be configured to use at least one subnet in each AZ. Then, it will attempt to distribute instances evenly across AZs and automatically cycle through AZs in case of temporary launch failures.

Diagram showing a VPC with subnets in 2 Availability Zones and an Autoscaling group managing groups of instances of different types

Operational best practices

The way that your workload is operated also impacts your ability to scale it when needed. Failure management and appropriate scaling techniques will help you maximize the availability of your environment.

Failure management

On-Demand capacity isn’t guaranteed to always be available. There might be short windows of time when AWS doesn’t have enough available On-Demand capacity to fulfill your specific request: as the availability of On-Demand capacity changes frequently, it’s important that your launch processes implement retry mechanisms.

Retries and fallbacks are managed automatically by EC2 Auto Scaling. But if you have a custom workflow to launch instances, it should be able to work with server error codes, in particular InsufficientInstanceCapacity or InternalError, by retrying the launch request. For a complete list of error codes for the EC2 API, please refer to our documentation.

Another option provided by EC2 is represented by EC2 Fleets. EC2 Fleet is a feature that helps to implement instance flexibility best practices. Instead of calling RunInstances with one instance type and retrying, EC2 Fleet in Instant mode considers all provided instance types, using a list of instances or Attribute Based Instance selection, and provisions capacity from the pools configured by the EC2 Fleet call where capacity was available.

Scaling technique

Launching EC2 instances as soon as you have an initial indication of increased load, in smaller batches and over a longer time span, helps increase your application performance and reliability while reducing costs and minimizing disruptions.

Two different scaling techniques that follow the increase in load are depicted. One scaling approach adds a large number of instances less frequently, while the second approach launches a smaller batch of instances more frequently. In the graph above, two different scaling techniques are depicted. Scaling approach #1 adds a large number of instances less frequently, while approach #2 launches a smaller batch of instances more frequently. Adopting the first approach risks your application not being able to sustain the increase in load in a timely manner. This will potentially cause an impact on end users and leave the operations team with little time to resolve.

Effective capacity planning

On-Demand Instances are best suited for applications with irregular, uninterruptible workloads. Interruptible workloads can avail of Spot Instances that pick from spare EC2 capacity. They cost less than On-Demand Instances but can be interrupted with a two-minute warning.

If your workload has a stable baseline utilization that hardly changes over time, then you can reserve capacity for your baseline usage of EC2 instances using open On-Demand Capacity Reservations and cover them with Savings Plans to get discounted rates with a one-year or three-year commitment, with the latter offering the bigger discounts.

Open On-Demand Capacity Reservations and Savings Plans aren’t tightly related to the EC2 instances that they cover at a certain point in time. Rather they shift to other usage, matching all of the parameters of the respective On-Demand Capacity Reservation or Savings Plan (e.g., Instance Type, Operating System, AZ, tenancy) in your account or across accounts for which you have sharing enabled. This lets you be dynamic even with your stable baseline. For example, during a rolling update or a blue/green deployment, On-Demand Capacity Reservations and Savings Plans will automatically cover any instances that match the respective criteria.

ODCR Fleets

There are times when you can’t apply all of the recommended mitigating actions in anticipation of a planned event. In those cases, you might want to use On-Demand Capacity Reservation Fleets to reserve capacity in advance for additional peace of mind. Capacity reservation fleets let you define capacity requests across multiple instance types, up to a target capacity that you specify. They can be created and managed using the AWS Command Line Interface (AWS CLI) and the AWS APIs.

Key concepts of Capacity Reservation Fleets are the total target capacity and the instance type weight. The instance type weight expresses the number of capacity units that each instance of a specific instance type counts toward the total target capacity.

Let’s say your workload is memory-bound, you expect to need 1,6TiB of RAM, and you want to use r6i instances. You can create a Capacity Reservation Fleet for r6i instances defining weights for each instance type in the family based on the relative amount of memory that they have in an instance type specification json file.

instanceTypeSpecification.json:
[
    {             
        "InstanceType": "r6i.2xlarge",                       
        "InstancePlatform":"Linux/UNIX",            
        "Weight": 1,
        "AvailabilityZone":"eu-west-1a",        
        "EbsOptimized": true,           
        "Priority" : 3
    },
    { 
        "InstanceType": "r6i.4xlarge",                        
        "InstancePlatform":"Linux/UNIX",            
        "Weight": 2,
        "AvailabilityZone":"eu-west-1a",        
        "EbsOptimized": true,            
        "Priority" : 2
    },
    {             
        "InstanceType": "r6i.8xlarge",                        
        "InstancePlatform":"Linux/UNIX",           
        "Weight": 4,
        "AvailabilityZone":"eu-west-1a",       
        "EbsOptimized": true,            
        "Priority" : 1
    }
]

Then, you want to use this specification to create a Capacity Reservation Fleet that takes care of the underlying Capacity Reservations needed to fulfill your request:

$ aws ec2 create-capacity-reservation-fleet \
--total-target-capacity 25 \
--allocation-strategy prioritized \
--instance-match-criteria open \
--tenancy default \
--end-date 2022-05-31T00:00:00.000Z \
--instance-type-specifications file://instanceTypeSpecification.json

In this example, I set the target capacity to 25, which is the number of r6i.2xlarge needed to get 1,6TiB of total memory across the fleet. As you might have noticed, Capacity Reservation Fleets can be created with an end date. They will automatically cancel themselves and the Capacity Reservations that they created when the end date is reached, so that you don’t need to.

AWS Infrastructure Event Management

Last but not least, our teams can offer the AWS Infrastructure Event Management (IEM) program. Part of select AWS Support offerings, the IEM program has been designed to help you with planning and executing events that impact your infrastructure on AWS. By requesting an IEM engagement, you will be supported by AWS experts during all of the phases of your event.Flow chart showing the steps and IEM is usually made of: 1. Event is planned 2. IEM is initiated 6-8 weeks in advance of the event 3. Infrastructure readiness is assessed and mitigations are applied 4. The event 5. Post-event reviewStarting from your business outcomes and success criteria, we’ll assess your infrastructure readiness for the event, evaluate risks, and recommend specific actions to mitigate them. The AWS experts will focus on your application architecture as a whole and dive deep into each of its components with your respective teams. They might also engage with other AWS teams to notify them of the upcoming event, and get specific prescriptive guidance when needed. During the event, AWS experts will have the context needed to help you resolve any issue that might arise as quickly as possible. The program is included in the Enterprise and Enterprise On-Ramp Support plans and is available to Business Support customers for an additional fee.

Conclusion

Whether you’re planning for a big future event, or you want to make sure that your application can withstand unexpected increases in traffic, it’s important that you consider what we discussed in this article:

  • Use as many instance types as you can, don’t limit your workload to use a single instance type when it could also use a lot more types
  • Distribute your EC2 instances across all AZs in the Region
  • Expect failures: manage retries and fallback options
  • Make use of EC2 Autoscaling and EC2 Fleet whenever possible
  • Avoid scaling spikes: start scaling earlier, in smaller chunks, and more frequently
  • Reserve capacity only when you really need to

For further study, we recommend the Well-Architected Framework Reliability and Operational Excellence pillars as starting points. Moreover, if you have an event coming up, talk to your Technical Account Manager, your Account Team, or contact us to find out how we can help!

NIST’s Post-Quantum Cryptography Standards

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2022/08/nists-post-quantum-cryptography-standards.html

Quantum computing is a completely new paradigm for computers. A quantum computer uses quantum properties such as superposition, which allows a qubit (a quantum bit) to be neither 0 nor 1, but something much more complicated. In theory, such a computer can solve problems too complex for conventional computers.

Current quantum computers are still toy prototypes, and the engineering advances required to build a functionally useful quantum computer are somewhere between a few years away and impossible. Even so, we already know that that such a computer could potentially factor large numbers and compute discrete logs, and break the RSA and Diffie-Hellman public-key algorithms in all of the useful key sizes.

Cryptographers hate being rushed into things, which is why NIST began a competition to create a post-quantum cryptographic standard in 2016. The idea is to standardize on both a public-key encryption and digital signature algorithm that is resistant to quantum computing, well before anyone builds a useful quantum computer.

NIST is an old hand at this competitive process, having previously done this with symmetric algorithms (AES in 2001) and hash functions (SHA-3 in 2015). I participated in both of those competitions, and have likened them to demolition derbies. The idea is that participants put their algorithms into the ring, and then we all spend a few years beating on each other’s submissions. Then, with input from the cryptographic community, NIST crowns a winner. It’s a good process, mostly because NIST is both trusted and trustworthy.

In 2017, NIST received eighty-two post-quantum algorithm submissions from all over the world. Sixty-nine were considered complete enough to be Round 1 candidates. Twenty-six advanced to Round 2 in 2019, and seven (plus another eight alternates) were announced as Round 3 finalists in 2020. NIST was poised to make final algorithm selections in 2022, with a plan to have a draft standard available for public comment in 2023.

Cryptanalysis over the competition was brutal. Twenty-five of the Round 1 algorithms were attacked badly enough to remove them from the competition. Another eight were similarly attacked in Round 2. But here’s the real surprise: there were newly published cryptanalysis results against at least four of the Round 3 finalists just months ago—moments before NIST was to make its final decision.

One of the most popular algorithms, Rainbow, was found to be completely broken. Not that it could theoretically be broken with a quantum computer, but that it can be broken today—with an off-the-shelf laptop in just over two days. Three other finalists, Kyber, Saber, and Dilithium, were weakened with new techniques that will probably work against some of the other algorithms as well. (Fun fact: Those three algorithms were broken by the Center of Encryption and Information Security, part of the Israeli Defense Force. This represents the first time a national intelligence organization has published a cryptanalysis result in the open literature. And they had a lot of trouble publishing, as the authors wanted to remain anonymous.)

That was a close call, but it demonstrated that the process is working properly. Remember, this is a demolition derby. The goal is to surface these cryptanalytic results before standardization, which is exactly what happened. At this writing, NIST has chosen a single algorithm for general encryption and three digital-signature algorithms. It has not chosen a public-key encryption algorithm, and there are still four finalists. Check NIST’s webpage on the project for the latest information.

Ian Cassels, British mathematician and World War II cryptanalyst, once said that “cryptography is a mixture of mathematics and muddle, and without the muddle the mathematics can be used against you.” This mixture is particularly difficult to achieve with public-key algorithms, which rely on the mathematics for their security in a way that symmetric algorithms do not. We got lucky with RSA and related algorithms: their mathematics hinge on the problem of factoring, which turned out to be robustly difficult. Post-quantum algorithms rely on other mathematical disciplines and problems—code-based cryptography, hash-based cryptography, lattice-based cryptography, multivariate cryptography, and so on—whose mathematics are both more complicated and less well-understood. We’re seeing these breaks because those core mathematical problems aren’t nearly as well-studied as factoring is.

The moral is the need for cryptographic agility. It’s not enough to implement a single standard; it’s vital that our systems be able to easily swap in new algorithms when required. We’ve learned the hard way how algorithms can get so entrenched in systems that it can take many years to update them: in the transition from DES to AES, and the transition from MD4 and MD5 to SHA, SHA-1, and then SHA-3.

We need to do better. In the coming years we’ll be facing a double uncertainty. The first is quantum computing. When and if quantum computing becomes a practical reality, we will learn a lot about its strengths and limitations. It took a couple of decades to fully understand von Neumann computer architecture; expect the same learning curve with quantum computing. Our current understanding of quantum computing architecture will change, and that could easily result in new cryptanalytic techniques.

The second uncertainly is in the algorithms themselves. As the new cryptanalytic results demonstrate, we’re still learning a lot about how to turn hard mathematical problems into public-key cryptosystems. We have too much math and an inability to add more muddle, and that results in algorithms that are vulnerable to advances in mathematics. More cryptanalytic results are coming, and more algorithms are going to be broken.

We can’t stop the development of quantum computing. Maybe the engineering challenges will turn out to be impossible, but it’s not the way to bet. In the face of all that uncertainty, agility is the only way to maintain security.

This essay originally appeared in IEEE Security & Privacy.

EDITED TO ADD: One of the four public-key encryption algorithms selected for further research, SIKE, was just broken.

Friday Squid Blogging: New Squid Species

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/08/friday-squid-blogging-new-squid-species.html

Seems like they are being discovered all the time:

In the past, the DEEPEND crew has discovered three new species of Bathyteuthids, a type of squid that lives in depths between 700 and 2,000 meters. The findings were validated and published in 2020. Another new squid species description is currently in review at the Bulletin of Marine Science.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Spring 2022 PCI DSS report available with seven services added to compliance scope

Post Syndicated from Michael Oyeniya original https://aws.amazon.com/blogs/security/spring-2022-pci-dss-report-available-with-seven-services-added-to-compliance-scope/

We’re continuing to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that seven new services have been added to the scope of our Payment Card Industry Data Security Standard (PCI DSS) certification. This provides our customers with more options to process and store their payment card data and architect their cardholder data environment (CDE) securely in AWS.

You can see the full list of services on our Services in Scope by Compliance program page. The seven new services are:

We were evaluated by Coalfire, a third-party Qualified Security Assessor (QSA). Customers can access the Attestation of Compliance (AOC) report demonstrating AWS’ PCI compliance status through AWS Artifact.

To learn more about our PCI program and other compliance and security programs, see the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Michael Oyeniya

Michael is a Compliance Program Manager at AWS on the Global Audits team, managing the PCI compliance program. He holds a Master’s degree in management and has over 18 years of experience in information technology security risk and control.

SIKE Broken

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/08/sike-broken.html

SIKE is one of the new algorithms that NIST recently added to the post-quantum cryptography competition.

It was just broken, really badly.

We present an efficient key recovery attack on the Supersingular Isogeny Diffie­-Hellman protocol (SIDH), based on a “glue-and-split” theorem due to Kani. Our attack exploits the existence of a small non-scalar endomorphism on the starting curve, and it also relies on the auxiliary torsion point information that Alice and Bob share during the protocol. Our Magma implementation breaks the instantiation SIKEp434, which aims at security level 1 of the Post-Quantum Cryptography standardization process currently ran by NIST, in about one hour on a single core.

News article.

Surveillance of Your Car

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/08/surveillance-of-your-car.html

TheMarkup has an extensive analysis of connected vehicle data and the companies that are collecting it.

The Markup has identified 37 companies that are part of the rapidly growing connected vehicle data industry that seeks to monetize such data in an environment with few regulations governing its sale or use.

While many of these companies stress they are using aggregated or anonymized data, the unique nature of location and movement data increases the potential for violations of user privacy.

Using certificate-based authentication for iOS applications with Amazon SNS

Post Syndicated from Sam Dengler original https://aws.amazon.com/blogs/compute/using-certificate-based-authentication-for-ios-applications-with-amazon-sns/

This blog post is written by Yashlin Naidoo, Arnav Thakur, Kim Read, Guilherme Silva.

Amazon SNS enables you to send notifications to a mobile push endpoint using a platform application endpoint by dispatching the notification on your application’s behalf. Push notifications for iOS apps are sent using Apple Push Notification Service (APNs).

To send push notifications using SNS for APNS certificate-based authentication, you must provide a set of credentials for connecting to the Apple Push Notification Service (see prerequisites for push). SNS supports using certificate-based authentication (.p12), in addition to the new token-based authentication (.p8).

Certificate-based authentication uses a provider certificate to establish a secure connection between your provider and APNs. These certificates are tied to a single application and are used to send notifications to this application. This approach can be useful when you haven’t migrated to the new token-based authentication.

For new applications, we recommend using token-based authentication as it provides improved security. It removes the need for yearly renewal of the certificates and can also be shared amongst multiple applications. To learn about how to use token-based authentication, visit Token-Based authentication for iOS applications with Amazon SNS in the AWS Compute Blog.

This blog shows step-by-step instructions on how to build an iOS application. You learn how to create a new certificate from your Apple developer account, and set up a platform application and endpoint in the SNS console. Next, you will learn how to test your application by sending a push notification via SNS to your device. Finally, you view the push notification delivered to your device.

Setting up your iOS application

This section will go over:

  • Creating an iOS application.
  • Creating a .p12 certificate to upload to SNS.

Prerequisites:

Creating an iOS application

  1. Create a new XCode project. Select iOS as the platform.

    New XCode project

    New XCode project

  2. Select your Apple Developer Account team and organization identifier.

    Select your Apple Developer Account team

    Select your Apple Developer Account team

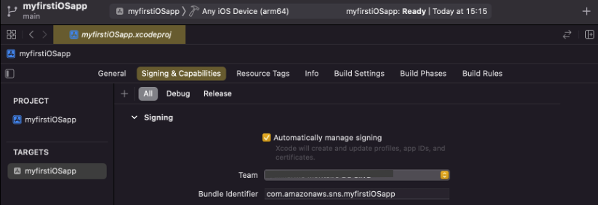
  3. In your project, go to Signing & Capabilities. Under signing, ensure that “Automatically manage signing” is checked and your team is selected.

    Signing & Capabilities

    Signing & Capabilities

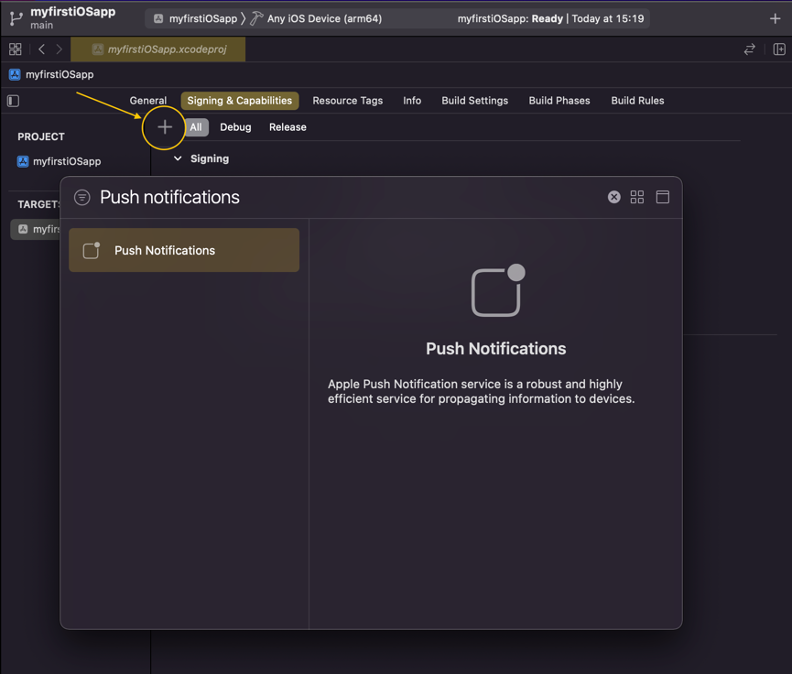
  4. To add the push notification capability to your application, select “+” and select Push Notifications.
    Add push notification capability

    Add push notification capability

    This step creates resources on your Apple Developer Account (the App ID and adds Push notification capability to it). You can also verify this in your Apple Developer Account.

  5. Add the following code to AppDelegate.swift:
        import UIKit
        import UserNotifications
    
        @main
        class AppDelegate: UIResponder, UIApplicationDelegate {
    
        func application(_ application: UIApplication, didFinishLaunchingWithOptions launchOptions: [UIApplication.LaunchOptionsKey: Any]?) -> Bool {
        // Override point for customization after application launch
    
        //Call to register for push notifications when launched
        registerForPushNotifications()
    
        return true
        }
    
        // MARK: UISceneSession Lifecycle
    
        func application(_ application: UIApplication, configurationForConnecting connectingSceneSession: UISceneSession, options: UIScene.ConnectionOptions) -> UISceneConfiguration {
        // Called when a new scene session is being created.
        // Use this method to select a configuration to create the new scene with.
        return UISceneConfiguration(name: "Default Configuration", sessionRole: connectingSceneSession.role)
        }
    
        func application(_ application: UIApplication, didDiscardSceneSessions sceneSessions: Set<UISceneSession>) {
        // Called when the user discards a scene session.
        // If any sessions were discarded while the application was not running, this will be called shortly after application:didFinishLaunchingWithOptions.
        // Use this method to release any resources that were specific to the discarded scenes, as they will not return.
        }
    
        func getNotificationSettings() {
        UNUserNotificationCenter.current().getNotificationSettings { settings in
        print("Notification settings: \(settings)")
    
        guard settings.authorizationStatus == .authorized else { return }
        DispatchQueue.main.async {
        UIApplication.shared.registerForRemoteNotifications()
        }
    
        }
        }
    
        func registerForPushNotifications() {
        //1 this handles all notification-related activities in the app including push notifications
        UNUserNotificationCenter.current()
    
        //2 this requests authorization to send the types of notifications specifies in the options
        .requestAuthorization(
        options: [.alert, .sound, .badge]) { [weak self] granted, _ in
        print("Permission granted: \(granted)")
        guard granted else { return }
        self?.getNotificationSettings()
        }
    
        }
    
        func application(
        _ application: UIApplication,
        didRegisterForRemoteNotificationsWithDeviceToken deviceToken: Data
        ) {
        let tokenParts = deviceToken.map { data in String(format: "%02.2hhx", data) }
        let token = tokenParts.joined()
        print("Device Token: \(token)")
        }
    
        func application(
        _ application: UIApplication,
        didFailToRegisterForRemoteNotificationsWithError error: Error
        ) {
        print("Failed to register: \(error)")
        }
    
        }
  6. Build and run the application on an iPhone. Note that the push notification feature does not work with a simulator.
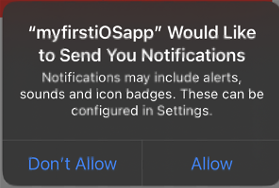
  7. On your phone, select “Allow” when prompted to allow push notifications.

    Allow push notifications

    Allow push notifications

  8. The debugger prints “Permission granted: true” if successful and returns the Device Token.

    Device token

    Device token

You have now configured an iOS application that can receive push notifications. Next, use the application to test sending push notifications with SNS using certificate-based authentication.

Creating a .p12 certificate to upload to SNS

After completing the previous step, you need:

  • An app identifier
  • A certificate signing request (CSR)
  • An SSL certificate

Create an identifier

  1. Log in to your Apple Developer Account.
  2. Choose Certificates, Identifiers & Profiles.
  3. In the Identifiers section, choose the Add button (+).
  4. In the Register a new identifier section, choose App IDs and select Continue.
  5. In the Select a type section, choose App, and select Continue.
  6. For Description, type the application description.
  7. For Bundle ID, use the Bundle ID assigned to your application. You can find this ID under Signing & Capabilities of your application in XCode (see step 3 under “Creating an application”).
  8. Under Capabilities, choose Push Notifications.
  9. Select Continue. In the Confirm your App ID panel, check that all values were entered correctly. The identifier should match your app ID and bundle ID.
  10. Select Register to register the new app ID.

Create a certificate signing request (CSR)

  1. Open Keychain Access located in /Applications/Utilities or search for it on Finder.
  2. Once opened, choose the tab Keychain Access Tab (next to the Apple icon). Navigate to Certificate Assistant and choose Request a Certificate from a Certificate Authority.
  3. Enter the Username, Email Address, Common Name and leave CA Email Address empty.
  4. Choose Saved to disk and choose Continue.

Create a certificate

  1. Log in to your Apple Developer Account.
  2. Choose Certificates, Identifiers & Profiles.
  3. In the Certificate section, select Create new certificate.
  4. Under services, choose your certificate: Apple Push Notification service SSL (Sandbox)/Apple Push Notification service SSL (Sandbox & Production).
  5. Keep Platform as iOS and choose App ID (Identifier) created previously.
  6. Upload the Certificate Signing Request created in the previous step and Download your certificate.

Create .p12 certificate to upload to SNS

  1. Once your certificate.cer file is downloaded (for example, “aps_development.cer”), open it to show in keychain access. Find Apple Development iOS Push Services: (Your Identifier Name/App ID Name) and ensure that the file is placed in the “Login” folder.
  2. Right-click and choose Export as file format .p12 and choose Save. Optionally, set a password.

Creating a new platform application using APNs certificate-based authentication

Prerequisites

To implement APNs certificate-based authentication from SNS, you must have:

  • An Apple Developer Account
  • An iOS mobile application

For creating a new SNS Platform Application that is used to store Push Notification Platform credentials, configurations and related configurations:

  1. Navigate to the SNS Console. Expand the Mobile menu and choose Create platform application.
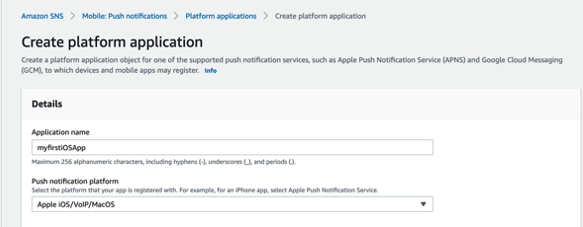
  2. For the Application name field, enter an application name such as “myfirstiOSapp”. For Push Notification Platform, select Apple iOS/ VoIP/ macOS.

    Create platform application

    Create platform application

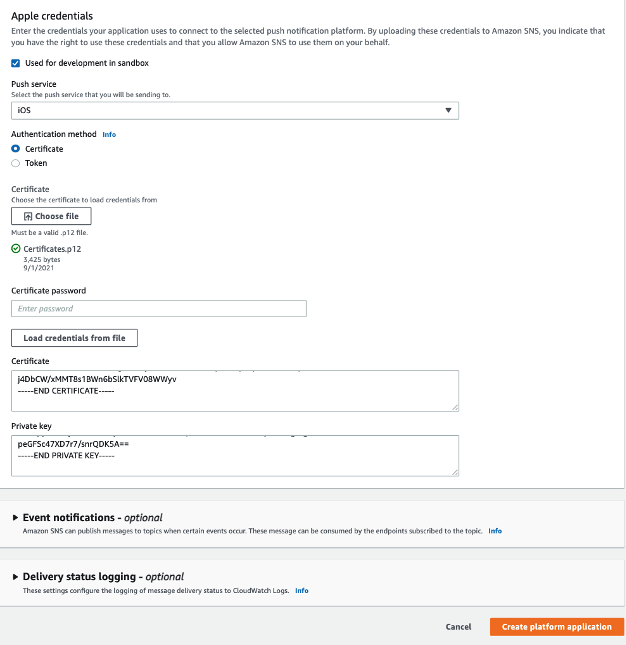
  3. Under the Apple Credentials section:
    1. If your application is in development, select the radio button for Used for development in sandbox. If your application is in production, uncheck Used for development in sandbox.
    2. For Push service, choose iOS and for Authentication method, choose Certificate.
    3. Under Certificate, select Choose file to upload the .p12 certificate file.
    4. If you configured a password while creating the certificate, enter this in the Certificate Password field.
    5. Choose Load Credentials from File to extract the Certificate and private key components.
  4. Event Notifications, Delivery Status Logging – Optional: Refer to the guide for enabling Delivery Status logs and the guide to set up Mobile Event related Notifications. More on this step can also be found in the best practices guide.

    Enter Apple credentials

    Enter Apple credentials

  5. Choose Create Platform Application. This creates a certificate-based authentication APNs Platform Application for iOS.

    Create platform application

    Create platform application

Creating a new platform endpoint using APNs token-based authentication

To send Push Notifications using SNS, a platform endpoint resource is created to store the destination address of the corresponding iOS application that is associated with the SNS platform application.

A destination address of a user’s device with the iOS application installed is identified by an unique device token. It is obtained once the app has registered successfully with APNs to receive push notifications. The details of the device token captured in the Platform Endpoint resource along with the configurations in the SNS Platform application are used in conjunction by the service to deliver a push notification message.

In the following steps, you create a new platform endpoint for a destination device that has the iOS application installed and is capable of receiving push notifications.

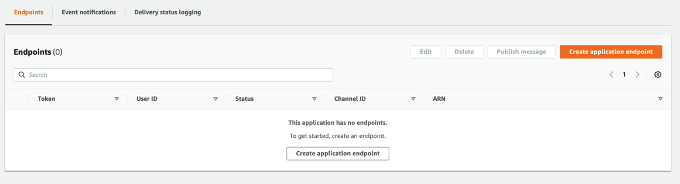
  1. Open your Platform Application. Choose Create Application Endpoint.

    Application endpoints list

    Application endpoints list

  2. Locate the Device token in the application logs of the iOS app provisioned earlier. Enter it in the Device Token Field.
  3. To store any additional arbitrary data for the endpoint, you can include in the User data field and choose Create application endpoint.

    Create application endpoint

    Create application endpoint

  4. Choose Create application endpoint and the details are shown on the console.

    Application endpoint detail

    Application endpoint detail

Testing a push notification from your device

In this section, you test sending a push notification to your device.

  1. From the SNS console, navigate to your platform endpoint and choose Publish message.
  2. Enter a message to send. This example uses a custom payload that allows you to provide additional APNs headers.

    Publish message

    Publish message

  3. Choose Publish message.
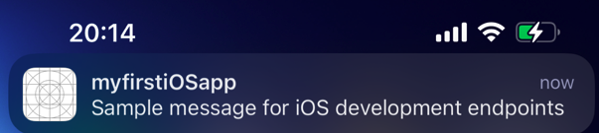
  4. The push notification is delivered to your device.

    Notification

    Notification

Conclusion

Developers send mobile push notifications for APNs certificate-based authentication by using a .p12 certificate to authenticate an Apple device endpoint. Certificate-based authentication ensures a secure connection through TLS (Transport Layer Security). The provider (SNS) initiates the request to APNs and validation from the provider and APNS is required to complete the secure connection.

Certificates expire annually and must be renewed to ensure that SNS can continue to deliver to the endpoint. In this post, you learn how to create an iOS application for APNs certificate-based authentication and integrate it with SNS to send push notifications to your device using a .p12 certificate to authenticate your application with the mobile endpoint.

To learn more about APNs certificate-based authentication with Amazon SNS, visit the Amazon SNS Developer Guide.

For more serverless learning resources, visit Serverless Land.

Ring Gives Videos to Police without a Warrant or User Consent

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/08/ring-gives-videos-to-police-without-a-warrant-or-user-consent.html

Amazon has revealed that it gives police videos from its Ring doorbells without a warrant and without user consent.

Ring recently revealed how often the answer to that question has been yes. The Amazon company responded to an inquiry from US Senator Ed Markey (D-Mass.), confirming that there have been 11 cases in 2022 where Ring complied with police “emergency” requests. In each case, Ring handed over private recordings, including video and audio, without letting users know that police had access to—and potentially downloaded—their data. This raises many concerns about increased police reliance on private surveillance, a practice that has long gone unregulated.

EFF writes:

Police are not the customers for Ring; the people who buy the devices are the customers. But Amazon’s long-standing relationships with police blur that line. For example, in the past Amazon has given coaching to police to tell residents to install the Ring app and purchase cameras for their homes—­an arrangement that made salespeople out of the police force. The LAPD launched an investigation into how Ring provided free devices to officers when people used their discount codes to purchase cameras.

Ring, like other surveillance companies that sell directly to the general public, continues to provide free services to the police, even though they don’t have to. Ring could build a device, sold straight to residents, that ensures police come to the user’s door if they are interested in footage—­but Ring instead has decided it would rather continue making money from residents while providing services to police.

CNet has a good explainer.

Slashdot thread.

За странните неща

Post Syndicated from original http://www.gatchev.info/blog/?p=2477

Убиецът на клошари

Вие сте полицейски служител във Варна. Една вечер, докато сте на дежурство, при вас няколко души довеждат някого. Твърдят, че са го видели да кани на брега двама клошари в лодка, да я подкарва навътре в морето и след половин час да се връща с лодката сам. Подозират го, че ги е убил и изхвърлил в морето.

Разпитвате човека. Той заявява, че клошарите петнят прекрасния град и затова той ги разчиства по описания от свидетелите начин. Арестувате го и го предавате на следствието.

Следствието провежда свои разпити, на които човекът и арестувалите го казват същото. Казват го и в съда. На базата на тези показания съдът осъжда свидетеля за убийство.

Нещо странно? Е, странното започва тук. След произнасянето на присъдата осъденият и свидетелите заявяват, че те са екип психолози. Че всичко, което са разказали, е измислица – защото е опит. И че целта на опита – която той бил постигнал блестящо – е да докаже, че правосъдието е ненадеждна институция. Че то не може да различи истински престъпник от мним, и затова е самоволно и опасно и не трябва да съществува.

А психиатрията?

Дивотии на търкалета ли е тяхното „доказателство“? Естествено. Извън експеримента тази ситуация би била толкова надеждно доказателство за вината на осъдения, колкото каквото и да е може да е надеждно в реалния свят. Някой да се съмнява?

Но точно такова нещо, и с аналогични мотиви, твърди проф. Дейвид Розенхан за психиатрията.

През 1973 г. той публикува статия как той и още няколко доброволци са посещавали психиатрични болници и са твърдели, че изпитват усещания, характерни за определени психични болести. Всички те били приети за лечение и лекувани. Това според него означава, че психиатрията всъщност не може да разпознае болния, тоест тя е самоволна и опасна, и не бива да съществува.

Розенхан е само един от многото апологети на т.нар. антипсихиатрия. Доказателствата на всички тях са от същата категория. Като се замислите, всъщност са доказателства, че психиатрията е полезна и нужна.

Как работи науката

Е, попресилих малко. Работата на науката е именно да поставя под съмнение нещата, които приемаме за аксиоми. И го върши най-добре, когато сред учените има и такива като Розенхан. Или като оня британски лорд, който в продължение на месец всеки ден изнасял концерт на цветята в градината си, за да види ще има ли ефект. Няма ли в науката купища налудничави твърдения, тя не може да е наука.

Науката обаче и пресява налудничавите твърдения, за да открие кои от тях са верни. На края на месеца споменатият лорд записва в дневника си: „Експериментът беше успешен – доказа се, че цветята не се влияят от концерти.“ При по-трудни проблеми подробно описаната опитна постановка се повтаря многократно от други учени, проверява се за несъвършенства и проблеми, следи се дали дава същите резултати, и т.н. До практически консенсус се стига след дълго доуточняване на опитните условия, чистене на проблеми, сравняване на данни, анализ на резултатите и т.н. Затова обикновено този консенсус е верен.

(Поне според знанията ни към момента. Напълно е възможно по-нататък да научим неща, които опровергават старите позиции. Тогава науката проверява всичко и допълва знанието си. Но отново по тази бавна и внимателна процедура – не само по нечие твърдение, че той е Айнщайн. Науката знае, че на един Айнщайн или Галилей се падат по милиони луди с кауза.)

И най-вече науката прави разлика между експеримент (специална постановка, която може да греши и доста често греши) и факт (нещо, обективно доказано по строги критерии на базата на голям брой експерименти). Точно както и между хипотеза (умозрителна конструкция, която твърди нещо, без да разполага с достатъчни доказателства) и теория (умозрителна конструкция, която вече има зад себе си достатъчно сериозни доказателства). Например възгледът на Айнщайн, че много неща във физиката са относителни, отначало е бил хипотеза. С времето обаче са се натрупали достатъчно доказателства за верността му, за да е вече теория.

(Затова хора, които казват за нещо „Това е само теория“, всъщност казват „Аз съм идиот, който не знае разликата между хипотеза и теория“. Оттам нататък да ги слушате е така безсмислено, както ако казват за нещо със същата пренебрежителност „А, това е само факт“.

Важи още повече за хора, които казват „Всеки си има свои истини / факти / реалност“. Те имат нужда да ги биете, докато им обяснявате, че ги биете само в тяхната реалност, а във вашата не ги пипвате с пръст, така че няма как да спрете. Да не ви занимават с претенциите си, вие не сте виновни, проблемът им е в тяхната си реалност. И най-вече да не охкат и да не се съпротивляват, защото правят собствените си твърдения за смях пред околните…)

А ежедневието?

Ежедневието, дори това на учените, не е научен процес. В него нещо се възприема, когато вече се е доказало като факт. В него правосъдието може да не е абсолютно съвършено, но е необходимо и полезно. Психиатрията – също. Както впрочем и разбирането как работи науката.

А кое е в крайна сметка странното, и защо го има?

Добре, а защо тогава толкова хора наоколо не са наясно с тези неща? Защо непрекъснато ще видите хора, убедени че всеки си има своя истина, свои факти и своя реалност?

Простичко е. Тези хора не приемат истините и фактите от обективната реалност. Поради особено тежък идиотизъм, дебелоглавие и/или други вътрешни проблеми. И затова си съчиняват своя реалност и факти. Точно както някои деца си имат въображаеми приятели, които са им разхвърлили играчките, казали са им да не си ядат закуската или са разляли боя върху албума със снимките на баба и дядо.

Ето затова тези хора са странни и изобщо ги има. Както е казал мъдрият шоп, „улавинята оди по ората – я улаво дръво не съм видел“.

Само че децата обикновено надрастват с времето въображаемите си приятели. Докато възрастните, които си съчиняват реалности, обикновено с времето само затъват все по-дълбоко в тях.

Затова, ако имате такива около себе си, бъдете възрастни и отговорни хора – проявете грижа за тях. Помогнете им да намерят път към лечение – по-нататък то ще става все по-трудно и ще отнема все повече време и усилия.

Въпреки че могат да отричат и психиатрията. Това е доказателство не че я няма или не работи, а че те имат нужда от грижите ѝ.

И докато не са станали мнозинство. Станат ли, е време да се спасявате нанякъде, където за тях се грижат както им е нужно.

Иначе рискувате тук те да се погрижат за вас както смятат, че ви е нужно.

Microsoft Zero-Days Sold and then Used

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/07/microsoft-zero-days-sold-and-then-used.html

Yet another article about cyber-weapons arms manufacturers and their particular supply chain. This one is about Windows and Adobe Reader zero-day exploits sold by an Austrian company named DSIRF.

There’s an entire industry devoted to undermining all of our security. It needs to be stopped.

New UFEI Rootkit

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/07/new-ufei-rootkit.html

Kaspersky is reporting on a new UFEI rootkit that survives reinstalling the operating system and replacing the hard drive. From an article:

The firmware compromises the UEFI, the low-level and highly opaque chain of firmware required to boot up nearly every modern computer. As the software that bridges a PC’s device firmware with its operating system, the UEFI—short for Unified Extensible Firmware Interface—is an OS in its own right. It’s located in an SPI-connected flash storage chip soldered onto the computer motherboard, making it difficult to inspect or patch the code. Because it’s the first thing to run when a computer is turned on, it influences the OS, security apps, and all other software that follows.

Both links have lots of technical details; the second contains a list of previously discovered UFEI rootkits. Also relevant are the NSA’s capabilities—now a decade old—in this area.

Securing Open-Source Software

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/07/securing-open-source-software.html

Good essay arguing that open-source software is a critical national-security asset and needs to be treated as such:

Open source is at least as important to the economy, public services, and national security as proprietary code, but it lacks the same standards and safeguards. It bears the qualities of a public good and is as indispensable as national highways. Given open source’s value as a public asset, an institutional structure must be built that sustains and secures it.

This is not a novel idea. Open-source code has been called the “roads and bridges” of the current digital infrastructure that warrants the same “focus and funding.” Eric Brewer of Google explicitly called open-source software “critical infrastructure” in a recent keynote at the Open Source Summit in Austin, Texas. Several nations have adopted regulations that recognize open-source projects as significant public assets and central to their most important systems and services. Germany wants to treat open-source software as a public good and launched a sovereign tech fund to support open-source projects “just as much as bridges and roads,” and not just when a bridge collapses. The European Union adopted a formal open-source strategy that encourages it to “explore opportunities for dedicated support services for open source solutions [it] considers critical.”

Designing an institutional framework that would secure open source requires addressing adverse incentives, ensuring efficient resource allocation, and imposing minimum standards. But not all open-source projects are made equal. The first step is to identify which projects warrant this heightened level of scrutiny—projects that are critical to society. CISA defines critical infrastructure as industry sectors “so vital to the United States that [its] incapacity or destruction would have a debilitating impact on our physical or economic security or public health or safety.” Efforts should target the open-source projects that share those features.

Apple’s Lockdown Mode

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/07/apples-lockdown-mode-2.html

I haven’t written about Apple’s Lockdown Mode yet, mostly because I haven’t delved into the details. This is how Apple describes it:

Lockdown Mode offers an extreme, optional level of security for the very few users who, because of who they are or what they do, may be personally targeted by some of the most sophisticated digital threats, such as those from NSO Group and other private companies developing state-sponsored mercenary spyware. Turning on Lockdown Mode in iOS 16, iPadOS 16, and macOS Ventura further hardens device defenses and strictly limits certain functionalities, sharply reducing the attack surface that potentially could be exploited by highly targeted mercenary spyware.

At launch, Lockdown Mode includes the following protections:

  • Messages: Most message attachment types other than images are blocked. Some features, like link previews, are disabled.
  • Web browsing: Certain complex web technologies, like just-in-time (JIT) JavaScript compilation, are disabled unless the user excludes a trusted site from Lockdown Mode.
  • Apple services: Incoming invitations and service requests, including FaceTime calls, are blocked if the user has not previously sent the initiator a call or request.
  • Wired connections with a computer or accessory are blocked when iPhone is locked.
  • Configuration profiles cannot be installed, and the device cannot enroll into mobile device management (MDM), while Lockdown Mode is turned on.

What Apple has done here is really interesting. It’s common to trade security off for usability, and the results of that are all over Apple’s operating systems—and everywhere else on the Internet. What they’re doing with Lockdown Mode is the reverse: they’re trading usability for security. The result is a user experience with fewer features, but a much smaller attack surface. And they aren’t just removing random features; they’re removing features that are common attack vectors.

There aren’t a lot of people who need Lockdown Mode, but it’s an excellent option for those who do.

News article.

EDITED TO ADD (7/31): An analysis of the effect of Lockdown Mode on Safari.

Leverage L2 constructs to reduce the complexity of your AWS CDK application

Post Syndicated from David Boldt original https://aws.amazon.com/blogs/devops/leverage-l2-constructs-to-reduce-the-complexity-of-your-aws-cdk-application/

The AWS Cloud Development Kit (AWS CDK) is an open-source software development framework to define your cloud application resources using familiar programming languages. AWS CDK uses the familiarity and expressive power of programming languages for modeling your applications. Constructs are the basic building blocks of AWS CDK apps. A construct represents a “cloud component” and encapsulates everything that AWS CloudFormation needs to create the component. Furthermore, AWS Construct Library lets you ease the process of building your application using predefined templates and logic. Three levels of constructs exist:

  • L1 – These are low-level constructs called Cfn (short for CloudFormation) resources. They’re periodically generated from the AWS CloudFormation Resource Specification. The name pattern is CfnXyz, where Xyz is name of the resource. When using these constructs, you must configure all of the resource properties. This requires a full understanding of the underlying CloudFormation resource model and its corresponding attributes.
  • L2 – These represent AWS resources with a higher-level, intent-based API. They provide additional functionality with defaults, boilerplate, and glue logic that you’d be writing yourself with L1 constructs. AWS constructs offer convenient defaults and reduce the need to know all of the details about the AWS resources that they represent. This is done while providing convenience methods that make it simpler to work with the resources and as a result creating your application.
  • L3 – These constructs are called patterns. They’re designed to complete common tasks in AWS, often involving multiple types of resources.

In this post, I show a sample architecture and how the complexity of an AWS CDK application is reduced by using L2 constructs.

Overview of the sample architecture

This solution uses Amazon API Gateway, AWS Lambda, and Amazon DynamoDB. I implement a simple serverless web application. The application receives a POST request from a user via API Gateway and forwards it to a Lambda function using proxy integration. The Lambda function writes the request body to a DynamoDB table.

The sample code can be found on GitHub.

The sample code can be found on GitHub.

Walkthrough

You can follow the instructions in the README file of the GitHub repository to deploy the stack. In the following walkthrough, I explain each logical unit and the differences when implementing it using L1 and L2 constructs. Before each code sample, I’ll show the path in the GitHub repository where you can find its source.

Create the DynamoDB table

First, I create a DynamoDB table to store the request content.

L1 construct

With L1 constructs, I must define each attribute of a table separately. For the DynamoDB table, these are keySchema, attributeDefinitions, and provisionedThroughput. They all require detailed CloudFormation knowledge, for example, how a keyType is defined.

lib/level1/database/infrastructure.ts

this.cfnDynamoDbTable = new dynamodb.CfnTable(
   this, 
   "CfnDynamoDbTable", 
   {
      keySchema: [
         {
            attributeName: props.attributeName,
            keyType: "HASH",
         },
      ],
      attributeDefinitions: [
         {
            attributeName: props.attributeName,
            attributeType: "S",
         },
      ],
      provisionedThroughput: {
         readCapacityUnits: 5,
         writeCapacityUnits: 5,
      },
   },
);

L2 construct

The corresponding L2 construct lets me use the default values for readCapacity (5) and writeCapacity (5). To further reduce the complexity, I define the attributes and the partition key simultaneously. In addition, I utilize the dynamodb.AttributeType.STRING enum.

lib/level2/database/infrastructure.ts

this.dynamoDbTable = new dynamodb.Table(
   this, 
   "DynamoDbTable", 
   {
      partitionKey: {
         name: props.attributeName,
         type: dynamodb.AttributeType.STRING,
      },
   },
);

Create the Lambda function

Next, I create a Lambda function which receives the request and stores the content in the DynamoDB table. The runtime code uses Node.js.

L1 construct

When creating a Lambda function using L1 construct, I must specify all of the properties at creation time – the business logic code location, runtime, and the function handler. This includes the role for the Lambda function to assume. As a result, I must provide the Attribute Resource Name (ARN) of the role. In the “Granting permissions” sections later in this post, I show how to create this role.

lib/level1/api/infrastructure.ts

const cfnLambdaFunction = new lambda.CfnFunction(
   this, 
   "CfnLambdaFunction", 
   {
      code: {
         zipFile: fs.readFileSync(
            path.resolve(__dirname, "runtime/index.js"),
            "utf8"
         ),
      },
      role: this.cfnIamLambdaRole.attrArn,
      runtime: "nodejs16.x",
      handler: "index.handler",
      environment: {
         variables: {
            TABLE_NAME: props.dynamoDbTableArn,
         },
      },
   },
);

L2 construct

I can achieve the same result with less complexity by leveraging the NodejsFunction L2 construct for Lambda function. It sets a default version for Node.js runtime unless another one is explicitly specified. The construct creates a Lambda function with automatic transpiling and bundling of TypeScript or Javascript code. This results in smaller Lambda packages that contain only the code and dependencies needed to run the function, and it uses esbuild under the hood. The Lambda function handler code is located in the runtime directory of the API logical unit. I provide the path to the Lambda handler file in the entry property. I don’t have to specify the handler function name, because the NodejsFunction construct uses the handler name by default. Moreover, a Lambda execution role isn’t required to be provided during L2 Lambda construct creation. If no role is specified, then a default one is generated which has permissions for Lambda execution. In the section ‘Granting Permissions’, I describe how to customize the role after creating the construct.

lib/level2/api/infrastructure.ts

this.lambdaFunction = new lambda_nodejs.NodejsFunction(
   this, 
   "LambdaFunction", 
   {
      entry: path.resolve(__dirname, "runtime/index.ts"),
      runtime: lambda.Runtime.NODEJS_16_X,
      environment: {
         TABLE_NAME: props.dynamoDbTableName,
      },
   },
);

Create API Gateway REST API

Next, I define the API Gateway REST API to receive POST requests with Cross-origin resource sharing (CORS) enabled.

L1 construct

Every step, from creating a new API Gateway REST API, to the deployment process, must be configured individually. With an L1 construct, I must have a good understanding of CORS and the exact configuration of headers and methods.

Furthermore, I must know all of the specifics, such as for the Lambda integration type I must know how to construct the URI.

lib/level1/api/infrastructure.ts

const cfnApiGatewayRestApi = new apigateway.CfnRestApi(
   this, 
   "CfnApiGatewayRestApi", 
   {
      name: props.apiName,
   },
);

const cfnApiGatewayPostMethod = new apigateway.CfnMethod(
   this, 
   "CfnApiGatewayPostMethod", 
   {
      httpMethod: "POST",
      resourceId: cfnApiGatewayRestApi.attrRootResourceId,
      restApiId: cfnApiGatewayRestApi.ref,
      authorizationType: "NONE",
      integration: {
         credentials: cfnIamApiGatewayRole.attrArn,
         type: "AWS_PROXY",
         integrationHttpMethod: "ANY",
         uri:
            "arn:aws:apigateway:" +
            Stack.of(this).region +
            ":lambda:path/2015-03-31/functions/" +
            cfnLambdaFunction.attrArn +
            "/invocations",
            passthroughBehavior: "WHEN_NO_MATCH",
      },
   },
);

const CfnApiGatewayOptionsMethod = new apigateway.CfnMethod(
    this,
    "CfnApiGatewayOptionsMethod",
   {    
      // fields omitted
   },
);

const cfnApiGatewayDeployment = new apigateway.CfnDeployment(
    this,
    "cfnApiGatewayDeployment",
    {
      restApiId: cfnApiGatewayRestApi.ref,
      stageName: "prod",
    },
);

L2 construct

Creating an API Gateway REST API with CORS enabled is simpler with L2 constructs. I can leverage the defaultCorsPreflightOptions property and the construct builds the required options method. To set origins and methods, I can use the apigateway.Cors enum. To configure the Lambda proxy option, all I need to do is to set the proxy variable in the method to true. A default deployment is created automatically.

lib/level2/api/infrastructure.ts

this.api = new apigateway.RestApi(
   this, 
   "ApiGatewayRestApi", 
   {
      defaultCorsPreflightOptions: {
         allowOrigins: apigateway.Cors.ALL_ORIGINS,
         allowMethods: apigateway.Cors.ALL_METHODS,
      },
   },
);

this.api.root.addMethod(
    "POST",
    new apigateway.LambdaIntegration(this.lambdaFunction, {
      proxy: true,
    })
);

Granting permissions

In the sample application, I must give permissions to two different resources:

  1.  API Gateway REST API to invoke the Lambda function.
  2. Lambda function to write data to the DynamoDB table.

L1 construct

For both resources, I must define AWS Identity and Access Management (IAM) roles. This requires in-depth knowledge of IAM, how policies are structured, and which actions are required. In the following code snippet, I start by creating the policy documents. Afterward, I create a role for each resource. These are provided at creation time to the corresponding constructs as shown earlier.

lib/level1/api/infrastructure.ts

const cfnLambdaAssumeIamPolicyDocument = {
    // fields omitted
};

this.cfnLambdaIamRole = new iam.CfnRole(
   this, 
   "cfnLambdaIamRole", 
   {
      assumeRolePolicyDocument: cfnLambdaAssumeIamPolicyDocument,
      managedPolicyArns: [
        "arn:aws:iam::aws:policy/service-role/AWSLambdaBasicExecutionRole",
      ],
   },
);
    
const cfnApiGatewayAssumeIamPolicyDocument = {
   // fields omitted
};

const cfnApiGatewayInvokeLambdaIamPolicyDocument = {
   Version: "2012-10-17",
   Statement: [
      {
         Action: ["lambda:InvokeFunction"],
         Resource: [cfnLambdaFunction.attrArn],
         Effect: "Allow",
      },
   ],
};

const cfnApiGatewayIamRole = new iam.CfnRole(
   this, 
   "cfnApiGatewayIamRole", 
   {
      assumeRolePolicyDocument: cfnApiGatewayAssumeIamPolicyDocument,
      policies: [{
         policyDocument: cfnApiGatewayInvokeLambdaIamPolicyDocument,
         policyName: "ApiGatewayInvokeLambdaIamPolicy",
      }],
   },
);

The database construct exposes a function to grant write access to any IAM role. The function creates a policy, which allows dynamodb:PutItem on the database table and adds it as an additional policy to the role.

lib/level1/database/infrastructure.ts

grantWriteData(cfnIamRole: iam.CfnRole) {
   const cfnPutDynamoDbIamPolicyDocument = {
      Version: "2012-10-17",
      Statement: [
         {
            Action: ["dynamodb:PutItem"],
            Resource: [this.cfnDynamoDbTable.attrArn],
            Effect: "Allow",
         },
      ],
   };

    cfnIamRole.policies = [{
        policyDocument: cfnPutDynamoDbIamPolicyDocument,
        policyName: "PutDynamoDbIamPolicy",
    }];
}

At this point, all permissions are in place, except that Lambda function doesn’t have permissions to write data to the DynamoDB table yet. To grant write access, I call the grantWriteData function of the Database construct with the IAM role of the Lambda function.

lib/deployment.ts

database.grantWriteData(api.cfnLambdaIamRole)

L2 construct

Creating an API Gateway REST API with the LambdaIntegration construct generates the IAM role and attaches the role to the API Gateway REST API method. Giving the Lambda function permission to write to the DynamoDB table can be achieved with the following single line:

lib/deployment.ts

database.dynamoDbTable.grantWriteData(api.lambdaFunction);

Using L3 constructs

To reduce complexity even further, I can leverage L3 constructs. In the case of this sample architecture, I can utilize the LambdaRestApi construct. This construct uses a default Lambda proxy integration. It automatically generates a method and a deployment, and grants permissions. As a result, I can achieve the same with even less code.

const restApi = new apigateway.LambdaRestApi(
   this, 
   "restApiLevel3", 
   {
      handler: this.lambdaFunction,
      defaultCorsPreflightOptions: {
         allowOrigins: apigateway.Cors.ALL_ORIGINS,
         allowMethods: apigateway.Cors.ALL_METHODS
      },
   },
);

Cleanup

Many services in this post are available in the AWS Free Tier. However, using this solution may incur costs, and you should tear down the stack if you don’t need it anymore. Cleanup steps are included in the RADME file of the GitHub repository.

Conclusion

In this post, I highlight the difference between using L1 and L2 AWS CDK constructs with an example architecture. Leveraging L2 constructs reduces the complexity of your application by using predefined patterns, boiler plate, and glue logic. They offer convenient defaults and reduce the need to know all of the details about the AWS resources they represent, while providing convenient methods that make it simpler to work with the resource. Additionally, I showed how to reduce complexity for common tasks even further by using an L3 construct.

Visit the AWS CDK documentation to learn more about building resilient, scalable, and cost-efficient architectures with the expressive power of a programming language.

Author:

David Boldt

David Boldt is a Solutions Architect at AWS, based in Hamburg, Germany. David works with customers to enable them with best practices in their cloud journey. He is passionate about the internet of Things and how it can be leveraged to solve different challenges across industries.

Friday Squid Blogging: Bathyteuthis berryi Holding Eggs

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/07/friday-squid-blogging-bathyteuthis-berryi-holding-eggs.html

Image and video of a Bathyteuthis berryi carrying a few hundred eggs, taken at a depth of 4,650 feet.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Critical Vulnerabilities in GPS Trackers

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/07/critical-vulnerabilities-in-gps-trackers.html

This is a dangerous vulnerability:

An assessment from security firm BitSight found six vulnerabilities in the Micodus MV720, a GPS tracker that sells for about $20 and is widely available. The researchers who performed the assessment believe the same critical vulnerabilities are present in other Micodus tracker models. The China-based manufacturer says 1.5 million of its tracking devices are deployed across 420,000 customers. BitSight found the device in use in 169 countries, with customers including governments, militaries, law enforcement agencies, and aerospace, shipping, and manufacturing companies.

BitSight discovered what it said were six “severe” vulnerabilities in the device that allow for a host of possible attacks. One flaw is the use of unencrypted HTTP communications that makes it possible for remote hackers to conduct adversary-in-the-middle attacks that intercept or change requests sent between the mobile application and supporting servers. Other vulnerabilities include a flawed authentication mechanism in the mobile app that can allow attackers to access the hardcoded key for locking down the trackers and the ability to use a custom IP address that makes it possible for hackers to monitor and control all communications to and from the device.

The security firm said it first contacted Micodus in September to notify company officials of the vulnerabilities. BitSight and CISA finally went public with the findings on Tuesday after trying for months to privately engage with the manufacturer. As of the time of writing, all of the vulnerabilities remain unpatched and unmitigated.

These are computers and computer vulnerabilities, but because the computers are attached to cars, the vulnerabilities become potentially life-threatening. CISA writes:

These vulnerabilities could impact access to a vehicle fuel supply, vehicle control, or allow locational surveillance of vehicles in which the device is installed.

I wouldn’t have buried “vehicle control” in the middle of that sentence.