Докато Румен Радев ни уверява, че „евтиният петрол, за който е пригодена нашата рафинерия, е на два дни прав път през Черно море“, а Бойко Борисов – че „всички гласуват за ГЕРБ по любов“, Artemis II започна своето пътуване към и около Луната. Може да го следите в live stream канала на мисията:
Съветвам ви да го правите при всяка възможност, за да не забравяте, че винаги има надежда да бъдем на по-добро място. Било то и извън орбита. Така както прави и астронавтката Кристина Кох, част от 4-членния екипаж на борда на Orion, първата жена, която ще отиде до Луната и обратно, впечатляваща специалистка с рекордните 328 дни на Международната космическа станция и съпруга и майка, която е щастлива, че ще има едни десет дни, в които никой няма да ѝ се обажда по телефона с въпроса „А това къде ми е?“.
Обратно на Земята, чиято гравитация напоследък сякаш ни натиска повече от обикновено и където постоянно ни се налага да търсим едно или друго – я ключове, я смелост да отидем до магазина, където всичко е по 400 евро, я логика в действията на световните лидери.
Тук, долу, нещата са „още от същото“. Стоим на прага на нова криза, горе-долу с мащабите на ковидската, само че този път енергийна, предупреждават от Брюксел. Не е лоша идея, казват, да си работите от вкъщи и да не шофирате много-много, а ако шофирате, правете го бавно.
Ако веднага след видеото на Румен Радев, което линкнах по-горе, ви се зарежда рийл с плетене на една кука, значи сте направили най-доброто за себе си и за менталното си здраве. Ако обаче ви влиза Томислав Дончев с отговори на „Пет въпроса от младите хора“ (кои са тия млади хора?), от които става ясно, че България превъзхожда другите страни „с много неща“, не знам как да ви помогна. Освен да ви препоръчам текста на Веселин Златков за Варна и за „многото неща“, които са готови, но не са хубави в този град, управляван 10 години от ГЕРБ.
Във връзка с войната и световното лидерство споделям с вас карикатурата на Бил Брамхол за New York Daily News, препостната в X от английския профил на Иранската информационна агенция. Просто е толкова хубаво всичко!
A Western Cartoonist's Jab at Trump's Claims
"The Iranians you've been talking to for two days. Are they in the room with us now? pic.twitter.com/bXHmdhrOOP
Не мога да си представя живот без това, което изкуството дава. То те владее, поставя въпроси, тревожи те и в това е красотата му. В него са възможни много различни светове. И аз обичам да потъвам в тях. Но те също така вдъхновяват – независимо дали филм, книга или картина могат да породят у теб желание да създадеш нещо твое, да продължиш диалога.
Тодора говори за желанието да продължиш диалога. За съжаление, по някои теми въобще не сме го почвали. Или сме го повлекли в тотално грешна посока. Една от тях е „Какво е да остарееш в България?“. Или не говорим по нея, или я принизяваме до „ексклузивността“ на сутрешен блок, който прави „шокиращи разкрития“ в дом за възрастни хора.
За да започнем диалога по по-смислен начин, ви каним на прожекциите на документалния филм на Лина Кривошиева „Какво е да остарееш в България“.
Премиерата ще бъде в София на 5 април (тази неделя) от 15:00 ч. в Дома на киното. Всички останали места, дати и часове, както и повече информация за филма може да видите в публикацията за филма в сайта ни.
А в този разговор Лина разказва за личната си мотивация да тръгне към темата за остаряването. Тема, от която повечето от нас се боят, може би докато не си дадем сметка, че остаряването всъщност е привилегия. Как обаче изглежда тя в държава като нашата?
И понеже в „Тоест“ сме по разговорите – ако не сме ги почнали, си намираме повод, а ако сме ги стартирали, гледаме да не ги спираме – затова и в новия епизод на видеопоредицата ни „Тоест разговаряме“ (много разговор, много нещо!) продължаваме с диалозите по важни теми с нашите редовни автори.
На 4 април (тази събота) от 16:00 ч. в YouTube LiveВладислав Севов се среща с Надежда Цекулова, за да я пита „Какво му липсва на нашето здравеопазване?“, а тя да му отговори „А какво НЕ му липсва на нашето здравеопазване?!“. Разбира се, няма да е така, защото това ще е най-краткият стрийминг в историята на стриймингите, а и защото Надежда има доста да каже за системните дефицити в здравеопазването.
Да обобщя, за да няма неразбрали:
В събота (4 април) сте в 16:00 ч. в YouTube Liveза разговора с Надежда Цекулова за българското здравеопазване.
В неделя (5 април) сте в 15:00 ч. в Дома на киното за прожекцията на „Какво е да остарееш в България“.
През останалото време сте където пожелаете, но най-вече в сърцата на екипа на „Тоест“, защото, ако ви няма вас, верните читатели на медията, тя няма как да съществува.
Ако харесвате това, което правим, и го намирате за важно, но още не сте станали дарители, може да го направите с малък месечен абонамент, който би означавал много за нас.
Ако вече сте част от хората, които ни подкрепят, благодарим ви сърдечно! Четете и споделяйте съдържанието ни и разказвайте на вашите приятели какво ви е харесало в медията, за да продължи да я има.
Today’s filmmakers capture more footage than ever to maximize their creative options, often generating hundreds, if not thousands, of hours of raw material per season or franchise. Extracting the vital moments needed to craft compelling storylines from this sheer volume of media is a notoriously slow and punishing process. When editorial teams cannot surface these key moments quickly, creative momentum stalls and severe fatigue sets in.
Meanwhile, the broader search landscape is undergoing a profound transformation. We are moving beyond simple keyword matching toward AI-driven systems capable of understanding deep context and intent. Yet, while these advances have revolutionized text and image retrieval, searching through video, the richest medium for storytelling, remains a daunting “needle in a haystack” challenge.
The solution to this bottleneck cannot rely on a single algorithm. Instead, it demands orchestrating an expansive ensemble of specialized models: tools that identify specific characters, map visual environments, and parse nuanced dialogue. The ultimate challenge lies in unifying these heterogeneous signals, textual labels, and high-dimensional vectors into a cohesive, real-time intelligence. One that cuts through the noise and responds to complex queries at the speed of thought, truly empowering the creative process.
Why Video Search is Deceptively Complex
Since video is a multi-layered medium, building an effective search engine required us to overcome significant technical bottlenecks. Multi-modal search is exponentially more complex than traditional indexing: it demands the unification of outputs from multiple specialized models, each analyzing a different facet of the content to generate its own distinct metadata. The ultimate challenge lies in harmonizing these heterogeneous data streams to support rich, multi-dimensional queries in real time.
Unifying the Timeline
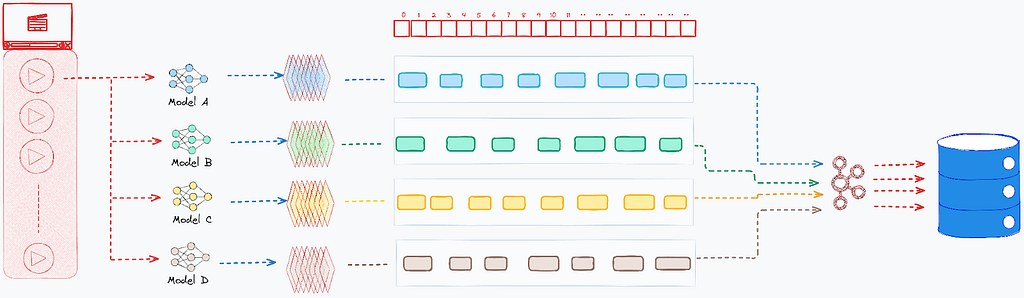
To ensure critical moments aren’t lost across scene boundaries, each model segments the video into overlapping intervals. The resulting metadata varies wildly, ranging from discrete text-based object labels to dense vector embeddings. Synchronizing these disjointed, multi-modal timelines into a unified chronological map presents a massive computational hurdle.
2. Processing at Scale
A standard 2,000-hour production archive can contain over 216 million frames. When processed through an ensemble of specialized models, this baseline explodes into billions of multi-layered data points. Storing, aligning, and intersecting this staggering volume of records while maintaining sub-second query latency far exceeds the capabilities of traditional database architectures.
3. Surfacing the Best Moments
Surface-level mathematical similarity is not enough to identify the most relevant clip. Because continuous shots naturally generate thousands of visually redundant candidates, the system must dynamically cluster and deduplicate results to surface the singular best match for a given scene. To achieve this, effective ranking relies on a sophisticated hybrid scoring engine that weighs symbolic text matches against semantic vector embeddings, ensuring both precision and interpretability.
4. Zero-Friction Search
For filmmakers, search is a stream-of-consciousness process, and a ten-second delay can disrupt the creative flow. Because sequential scanning of raw footage is fundamentally unscalable, our architecture is built to navigate and correlate billions of vectors and metadata records efficiently, operating at the speed of thought.
Figure 1: Unified Multimodal Result Processing
The Ingestion and Fusion Pipeline
To ensure system resilience and scalability, the transition from raw model output to searchable intelligence follows a decoupled, three-stage process:
1. Transactional Persistence
Raw annotations are ingested via high-availability pipelines and stored in our annotation service, which leverages Apache Cassandra for distributed storage. This stage strictly prioritizes data integrity and high-speed write throughput, guaranteeing that every piece of model output is safely captured.
Figure 2: Sample Scene Search Model Annotation Output
2. Offline Data Fusion
Once the annotation service securely persists the raw data, the system publishes an event via Apache Kafka to trigger an asynchronous processing job. Serving as the architecture’s central logic layer, this offline pipeline handles the heavy computational lifting out-of-band. It performs precise temporal intersections, fusing overlapping annotations from disparate models into cohesive, unified records that empower complex, multi-dimensional queries.
Cleanly decoupling these intensive processing tasks from the ingestion pipeline guarantees that complex data intersections never bottleneck real-time intake. As a result, the system maintains maximum uptime and peak responsiveness, even when processing the massive scale of the Netflix media catalog.
Temporal Bucketing and Intersection
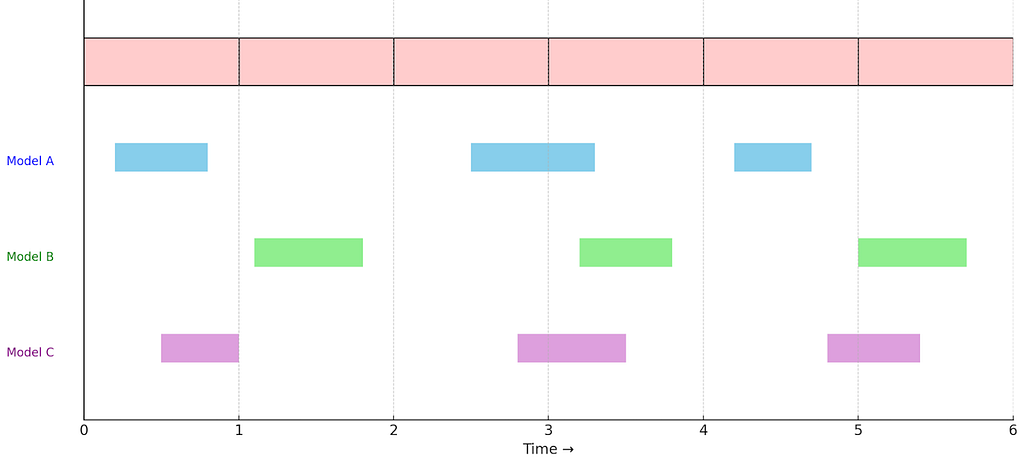
To achieve this intersection at scale, the offline pipeline normalizes disparate model outputs by mapping them into fixed-size temporal buckets (one-second intervals). This discretization process unfolds in three steps:
Bucket Mapping: Continuous detections are segmented into discrete intervals. For example, if a model detects a character (“Joey”) from seconds 2 through 8, the pipeline maps this continuous span of frames into seven distinct one-second buckets.
Annotation Intersection: When multiple models generate annotations for the exact same temporal bucket, such as character recognition “Joey” and scene detection “kitchen” overlapping in second 4, the system fuses them into a single, comprehensive record.
Optimized Persistence: These newly enriched records are written back to Cassandra as distinct entities. This creates a highly optimized, second-by-second index of multi-modal intersections, perfectly associating every fused annotation with its source asset.
Figure 3: Temporal Data Fusion with Fixed-Size Time Buckets
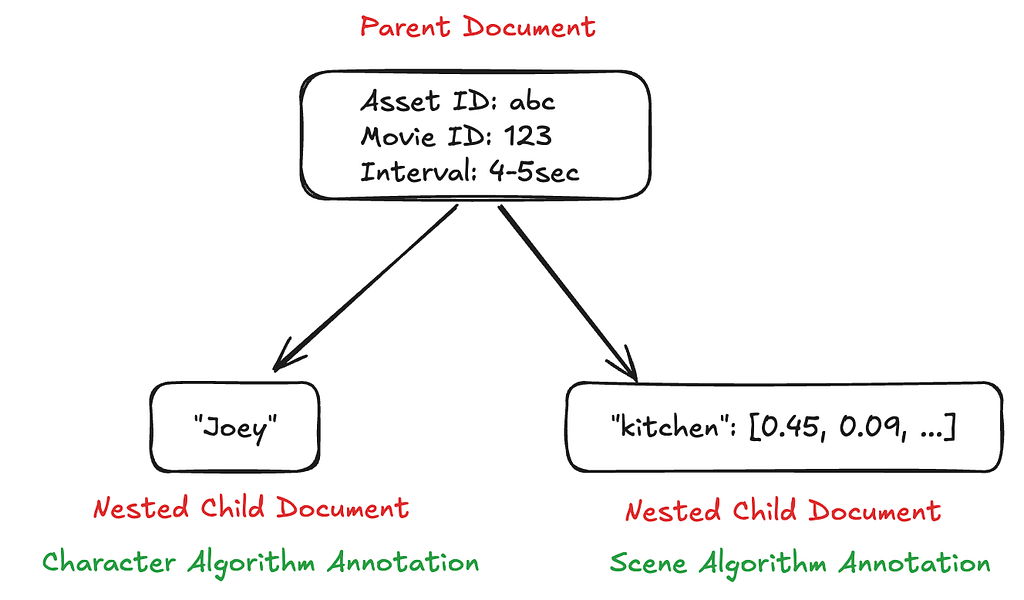
The following record shows the overlap of the character “Joey” and scene “kitchen” annotations during a 4 to 5 second window in a video asset:
Figure 4: Sample Intersection Record For Character + Scene Search
3. Indexing for Real Time Search
Once the enriched temporal buckets are securely persisted in Cassandra, a subsequent event triggers their ingestion into Elasticsearch.
To guarantee absolute data consistency, the pipeline executes upsert operations using a composite key (asset ID + time bucket) as the unique document identifier. If a temporal bucket already exists for a specific second of video, perhaps populated by an earlier model run, the system intelligently updates the existing record rather than generating a duplicate. This mechanism establishes a single, unified source of truth for every second of footage.
Architecturally, the pipeline structures each temporal bucket as a nested document. The root level captures the overarching asset context, while associated child documents house the specific, multi-modal annotation data. This hierarchical data model is precisely what empowers users to execute highly efficient, cross-annotation queries at scale.
The search service provides a high-performance interface for real-time discovery across the global Netflix catalog. Upon receiving a user request, the system immediately initiates a query preprocessing phase, generating a structured execution plan through three core steps:
Query Type Detection: Dynamically categorizes the incoming request to route it down the most efficient retrieval path.
Filter Extraction: Isolates specific semantic constraints such as character names, physical objects, or environmental contexts to rapidly narrow the candidate pool.
Vector Transformation: Converts raw text into high-dimensional, model-specific embeddings to enable deep, context-aware semantic matching.
Once generated, the system compiles this structured plan into a highly optimized Elasticsearch query, executing it directly against the pre-fused temporal buckets to deliver instantaneous, frame-accurate results.
Fine-Tuning Semantic Search
To support the diverse workflows of different production teams, the system provides fine-grained control over search behavior through configurable parameters:
Exact vs. Approximate Search: Users can toggle between exact k-Nearest Neighbors (k-NN) for uncompromising precision, and Approximate Nearest Neighbor (ANN) algorithms (such as HNSW) to maintain blazing speed when querying massive datasets.
Dynamic Similarity Metrics: The system supports multiple distance calculations, including cosine similarity and Euclidean distance. Because different models shape their high-dimensional vector spaces distinctly based on their underlying training architectures, the flexibility to swap metrics ensures that mathematical closeness perfectly translates to true semantic relevance.
Confidence Thresholding: By establishing strict minimum score boundaries for results, users can actively prune the “long tail” of low-probability matches. This aggressively filters out visual noise, guaranteeing that creative teams are not distracted and only review results that meet a rigorous standard of mathematical similarity.
Textual Analysis & Linguistic Precision
To handle the deep nuances of dialogue-heavy searches, such as isolating a character’s exact catchphrase amidst thousands of hours of speech, we implement a sophisticated text analysis strategy within Elasticsearch. This ensures that conversational context is captured and indexed accurately.
Phrase & Proximity Matching: To respect the narrative weight of specific lines (e.g., “Friends don’t lie” in Stranger Things), we leverage match-phrase queries with a configurable slop parameter. This guarantees the system retrieves the correct scene even if the user’s memory slightly deviates from the exact transcription.
N-Gram Analysis for Partial Discovery: Because video search is inherently exploratory, we utilize edge N-gram tokenizers to support “search-as-you-type” functionality. By actively indexing dialogue and metadata substrings, the system surfaces frame-accurate results the moment an editor begins typing, drastically reducing cognitive load.
Tokenization and Linguistic Stemming: To seamlessly support the global scale of the Netflix catalog, our analysis chain applies sophisticated stemming across multiple languages. This ensures a query for “running” automatically intersects with scenes tagged with “run” or “ran,” collapsing grammatical variations into a single, unified search intent.
Levenshtein Fuzzy Matching: To account for transcription anomalies or phonetic misspellings, we incorporate fuzzy search capabilities based on Levenshtein distance algorithms. This intelligent soft-matching approach ensures that high-value shots are never lost to minor data-entry errors or imperfect queries.
Aggregations and Flexible Grouping
The architecture operates at immense scale, seamlessly executing queries within a single title or across thousands of assets simultaneously. To combat result fatigue, the system leverages custom aggregations to intelligently cluster and group outputs based on specific parameters, such as isolating the top 5 most relevant clips of an actor per episode. This guarantees a diverse, highly representative return set, preventing any single asset from dominating the search results.
Search Response Curation
While temporal buckets are the internal mechanism for search efficiency, the system post-processes Elasticsearch results to reconstruct original time boundaries. The reconstruction process ensures results reflect narrative scene context rather than arbitrary intervals. Depending on the query intent, the system generates results based on two logic types:
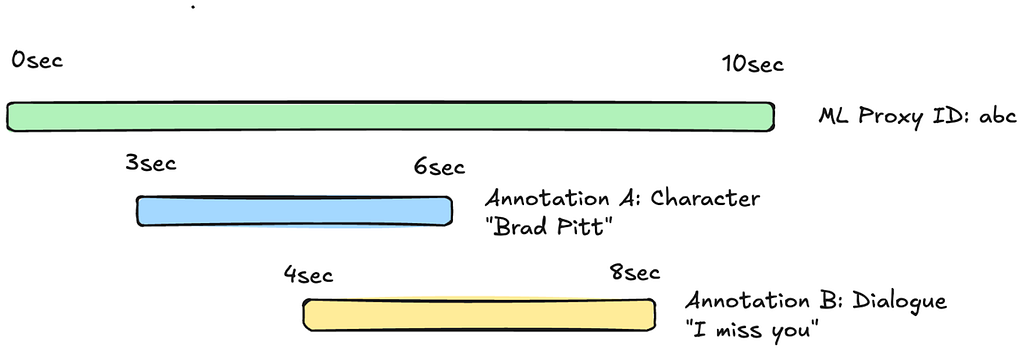
Figure 6: Depiction of Temporal Union vs Intersection
Union: Returns the full span of all matching annotations (3–8 sec), which prioritizes breadth, capturing any instance where a specified feature occurs.
Intersection: Returns only the exact overlapping duration of matching signals (4–6 sec). The intersection logic focuses on co-occurrence, isolating moments when multiple criteria align.
While our current architecture establishes a highly resilient and scalable foundation, it represents only the first phase of our multi-modal search vision. To continuously close the gap between human intuition and machine retrieval, our roadmap focuses on three core evolutions:
Natural Language Discovery: Transitioning from structured JSON payloads to fluid, conversational interfaces (e.g., “Find the best tracking shots of Tom Holland running on a roof”). This will abstract away underlying query complexity, allowing creatives to interact with the archive organically.
Adaptive Ranking: Implementing machine learning feedback loops to dynamically refine scoring algorithms. By continuously analyzing how editorial teams interact with and select clips, the system will self-tune its mathematical definition of semantic relevance over time.
Domain-Specific Personalization: Dynamically calibrating search weights and retrieval behaviors to match the exact context of the user. The platform will tailor its results depending on whether a team is cutting high-action marketing trailers, editing narrative scenes, or conducting deep archival research.
Ultimately, these advancements will elevate the platform from a highly optimized search engine into an intelligent creative partner, fully equipped to navigate the ever-growing complexity and scale of global video media.
Acknowledgements
We would like to extend our gratitude to the following teams and individuals whose expertise and collaboration were instrumental in the development of this system:
Today, we’re announcing the general availability of cross-account safeguards in Amazon Bedrock Guardrails, a new capability that enables centralized enforcement and management of safety controls across multiple AWS accounts within an organization.
With this new capability, you can specify a guardrail in a new Amazon Bedrock policy within the management account of your organization that automatically enforces configured safeguards across all member entities for every model invocation with Amazon Bedrock. This organization-wide implementation supports uniform protection across all accounts and generative AI applications with centralized control and management. This capability also offers flexibility to apply account-level and application-specific controls depending on use case requirements in addition to organizational safeguards.
Organization-level enforcements apply a single guardrail from your organization’s management account to all entities within the organization through policy settings. This guardrail automatically enforces filters across all member entities, including organizational units (OUs) and individual accounts, for all Amazon Bedrock model invocations.
Account-level enforcement enables automatic enforcement of configured safeguards across all Amazon Bedrock model invocations in your AWS account. The configured safeguards in the account-level guardrail apply to all inference API calls.
You can now establish and centrally manage dependable, comprehensive protection through a single, unified approach. This supports consistent adherence to corporate responsible AI requirements while significantly reducing the administrative burden of monitoring individual accounts and applications. Your security team no longer needs to oversee and verify configurations or compliance for each account independently.
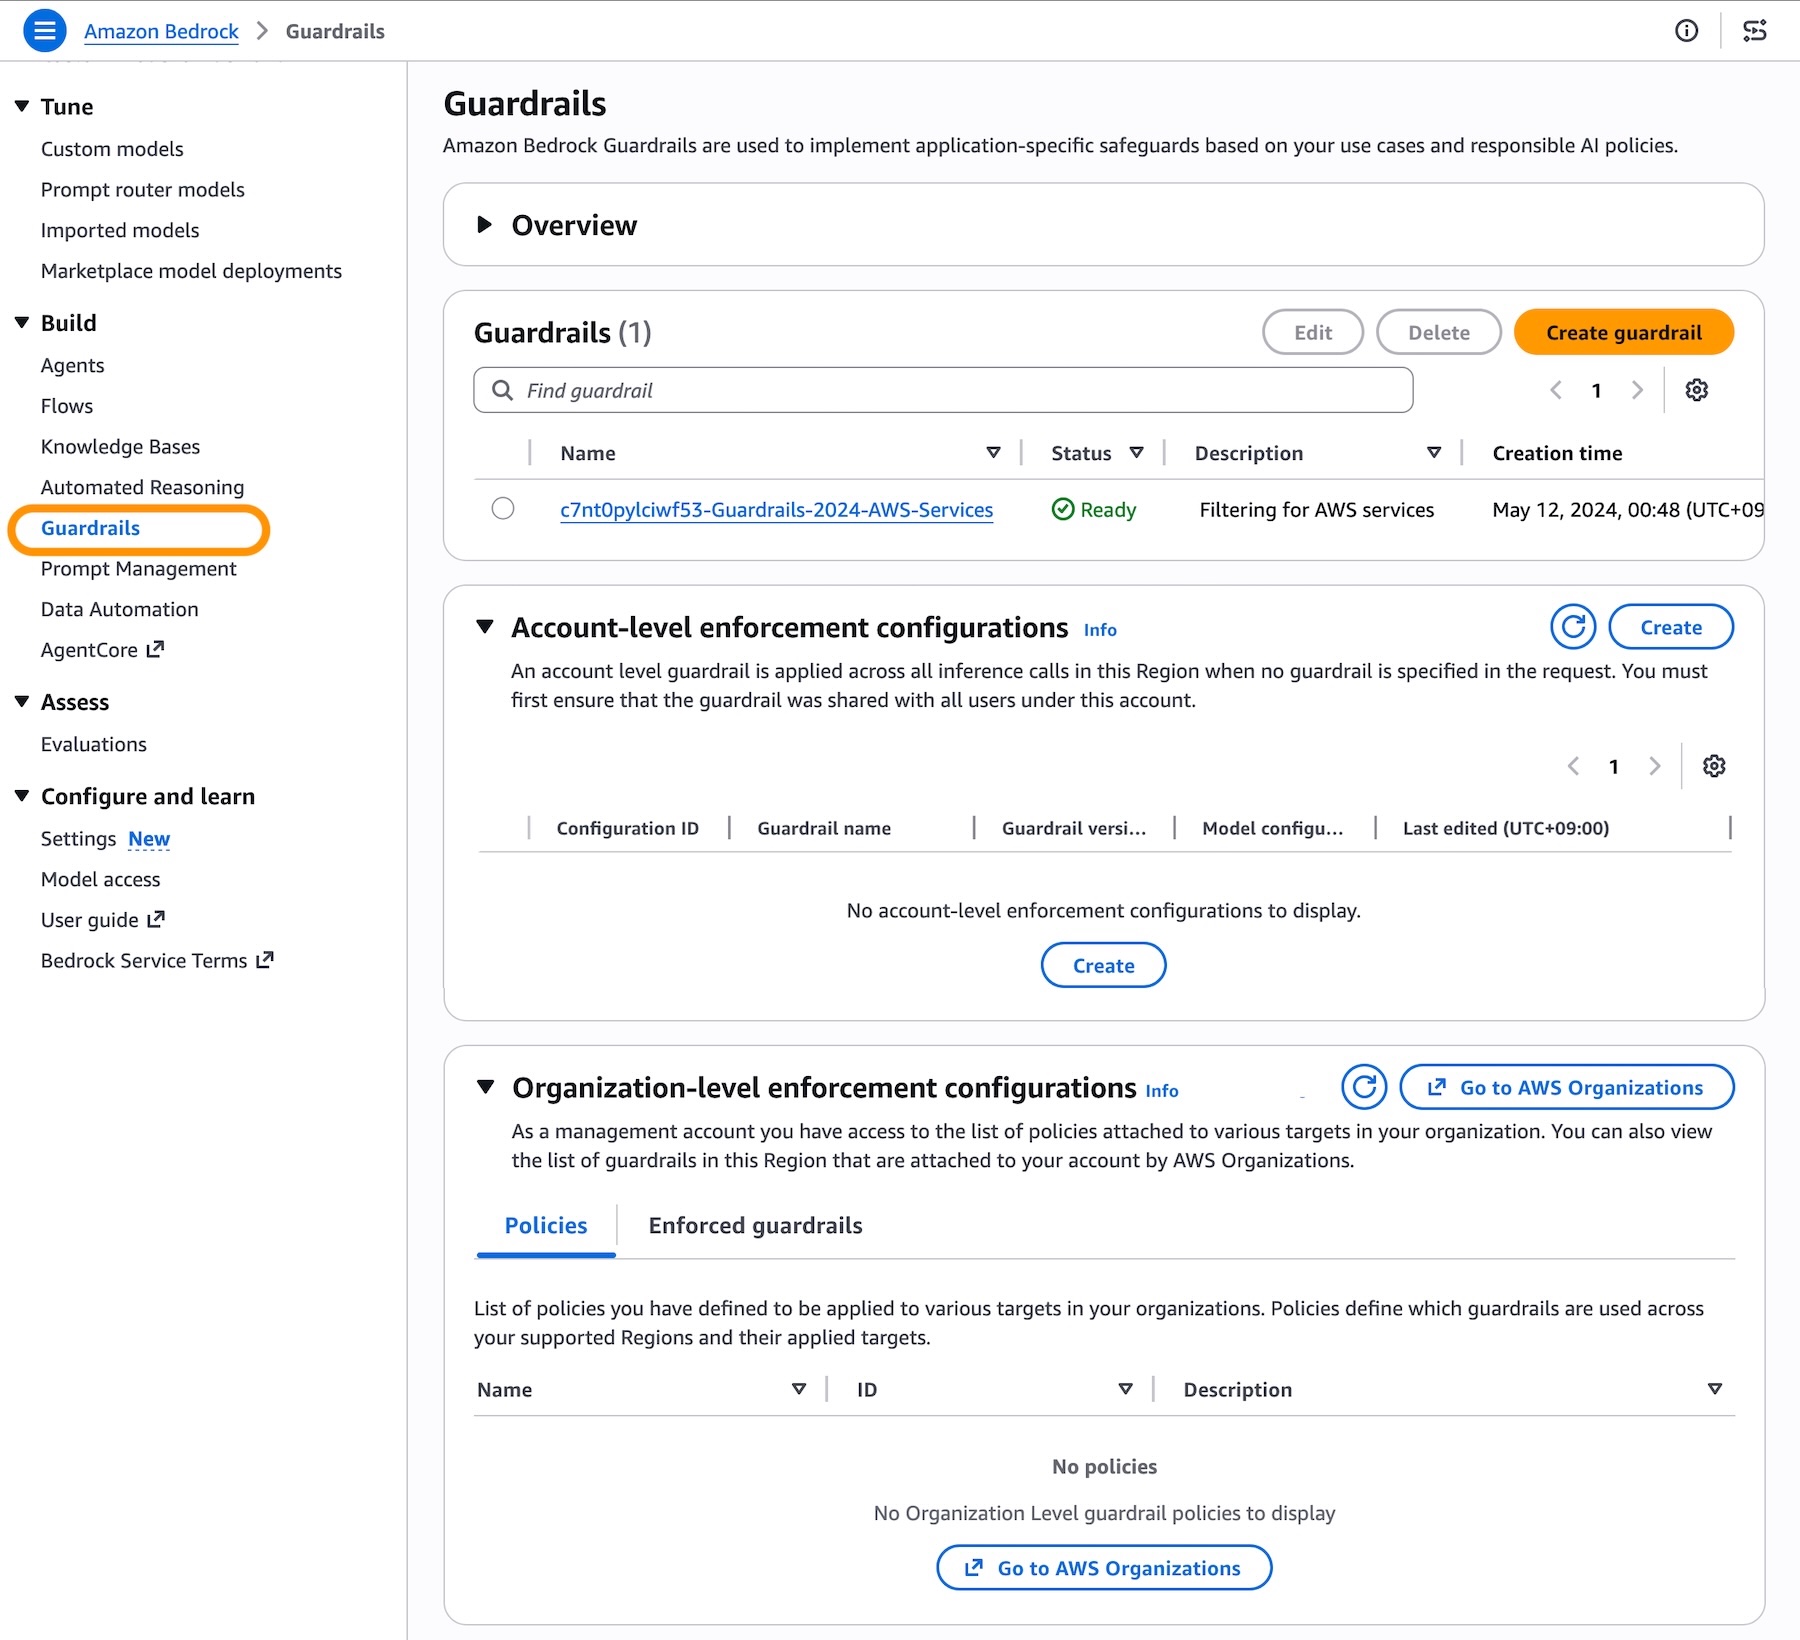
Getting started with centralized enforcement in Amazon Bedrock Guardrails You can get started with account-level and organization-level enforcement configuration in the Amazon Bedrock Guardrails console. Before the enforcement configuration, you need to create a guardrail with a particular version to support the guardrail configuration remains immutable and cannot be modified by member accounts and complete prerequisites for using the new capability such as resource-based policies for guardrails.
To enable account-level enforcement, choose Create in the section of Account-level enforcement configurations.
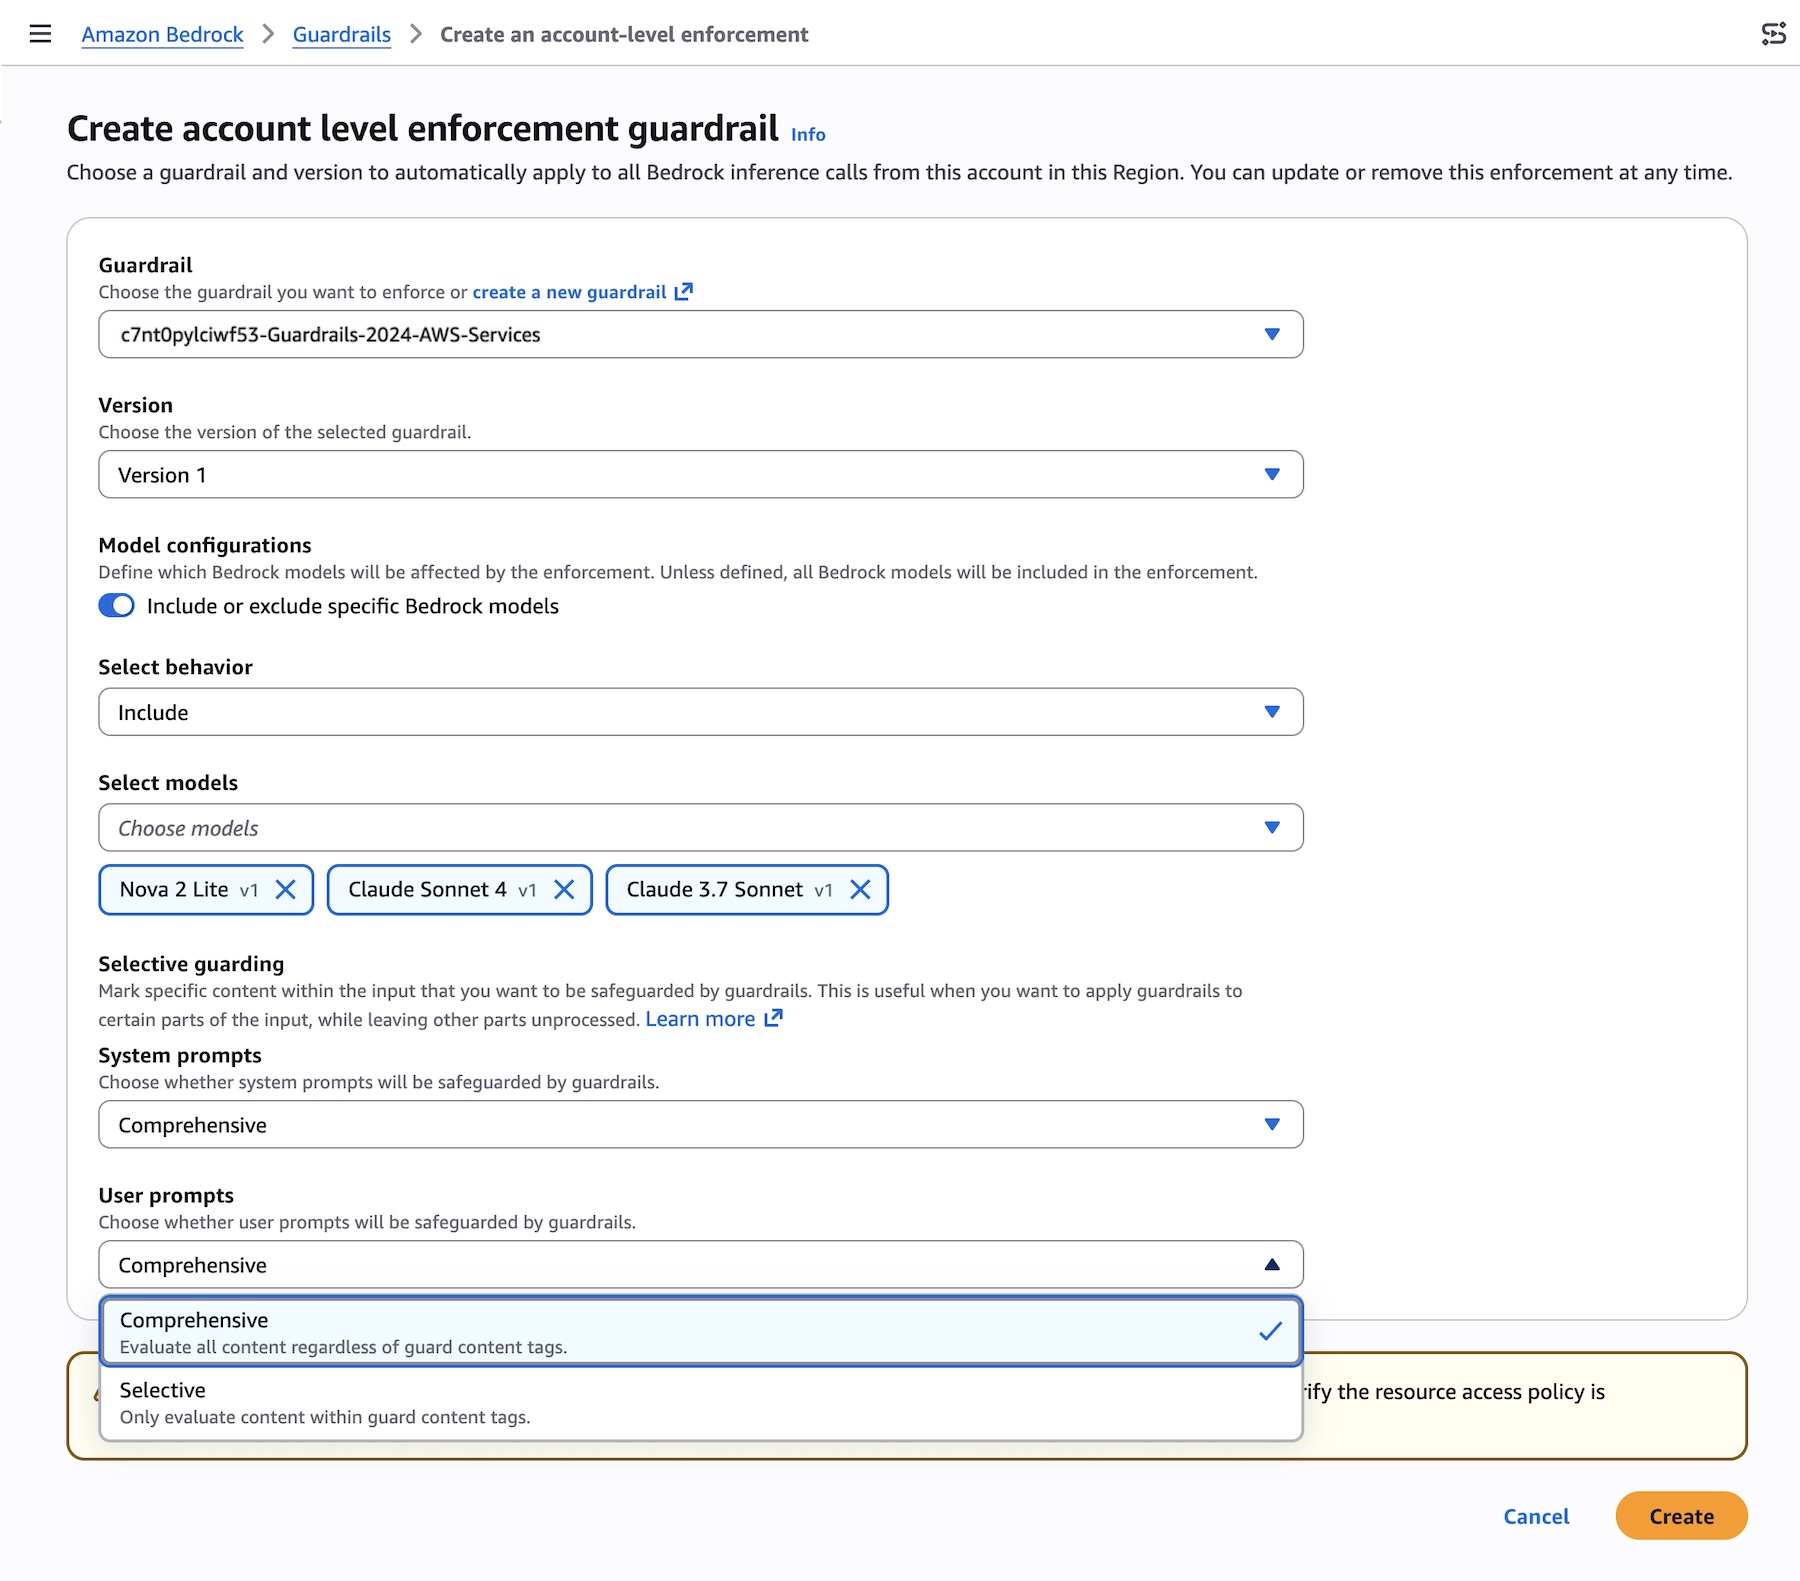
You can choose the guardrail and version to automatically apply to all Bedrock inference calls from this account in this Region. With general availability, we introduce the new feature defining which models will be affected by the enforcement with either Include or Exclude behavior.
You can also configure selective content guarding controls for system prompts and user prompts with either Comprehensive or Selective.
Use Comprehensive when you want to enforce guardrails on everything, regardless of what the caller tags. This is the safer default when you don’t want to rely on callers to correctly identify sensitive content.
Use Selective when you trust callers to tag the right content and want to reduce unnecessary guardrail processing. This is useful when callers handle a mix of pre-validated and user-generated content, and only need guardrails applied to specific portions.
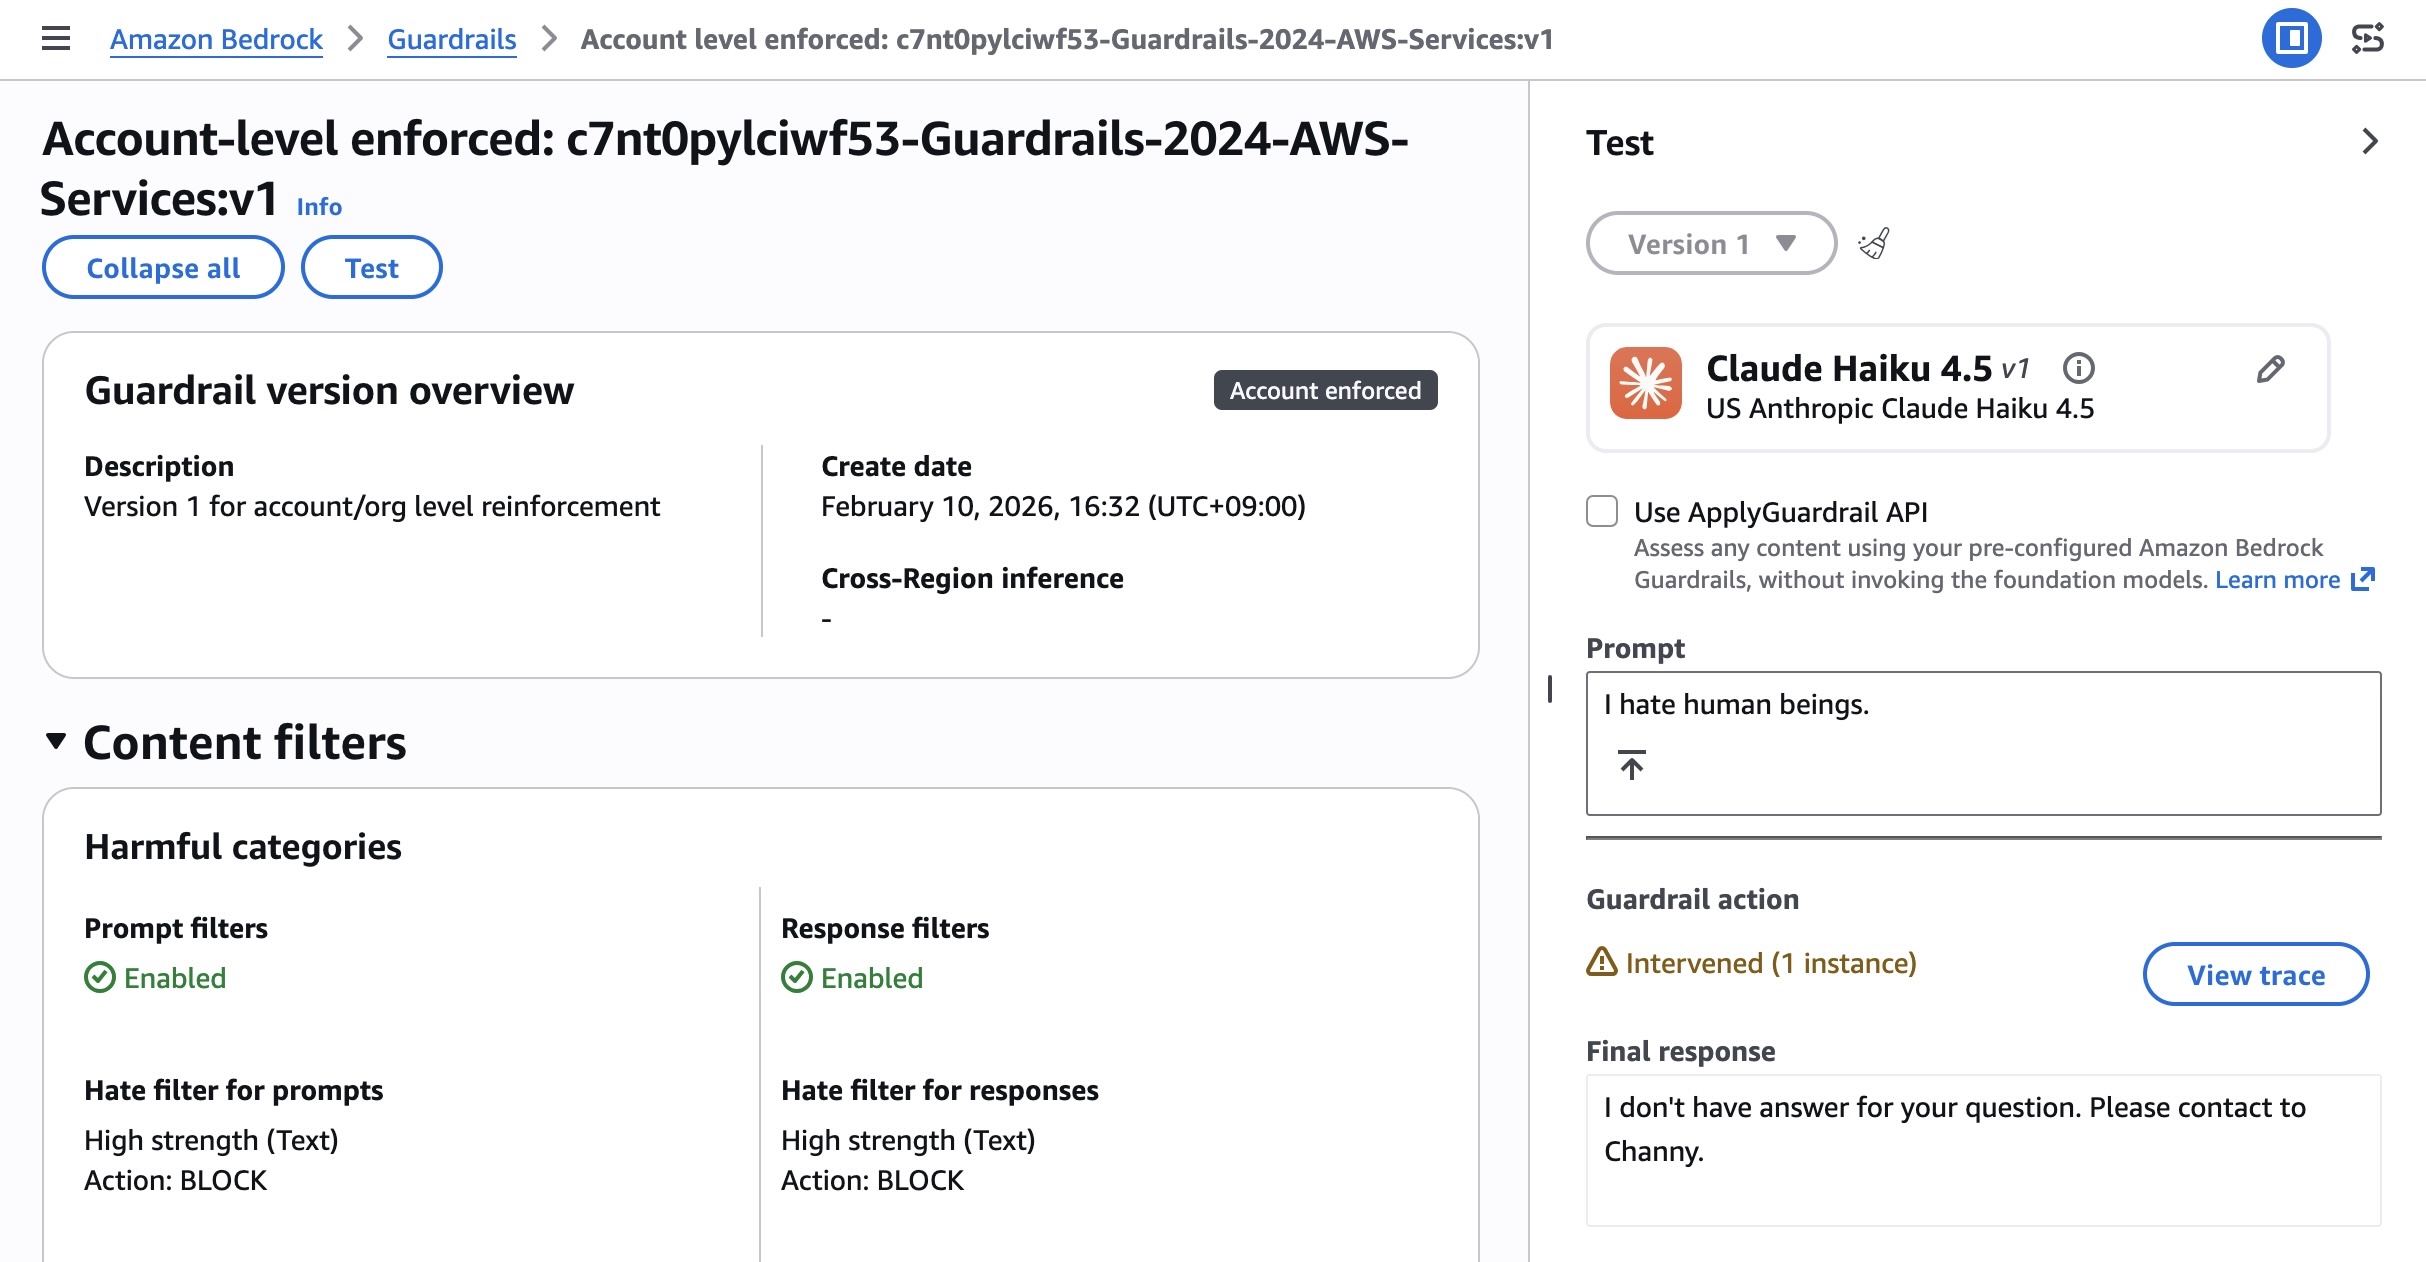
After creating the enforcement, you can test and verify enforcement using a role in your account. The account-enforced guardrail should automatically apply to both prompts and outputs.
Check the response for guardrail assessment information. The guardrail response will include enforced guardrail information. You can also test by making a Bedrock inference call using InvokeModel, InvokeModelWithResponseStream, Converse, or ConverseStream APIs.
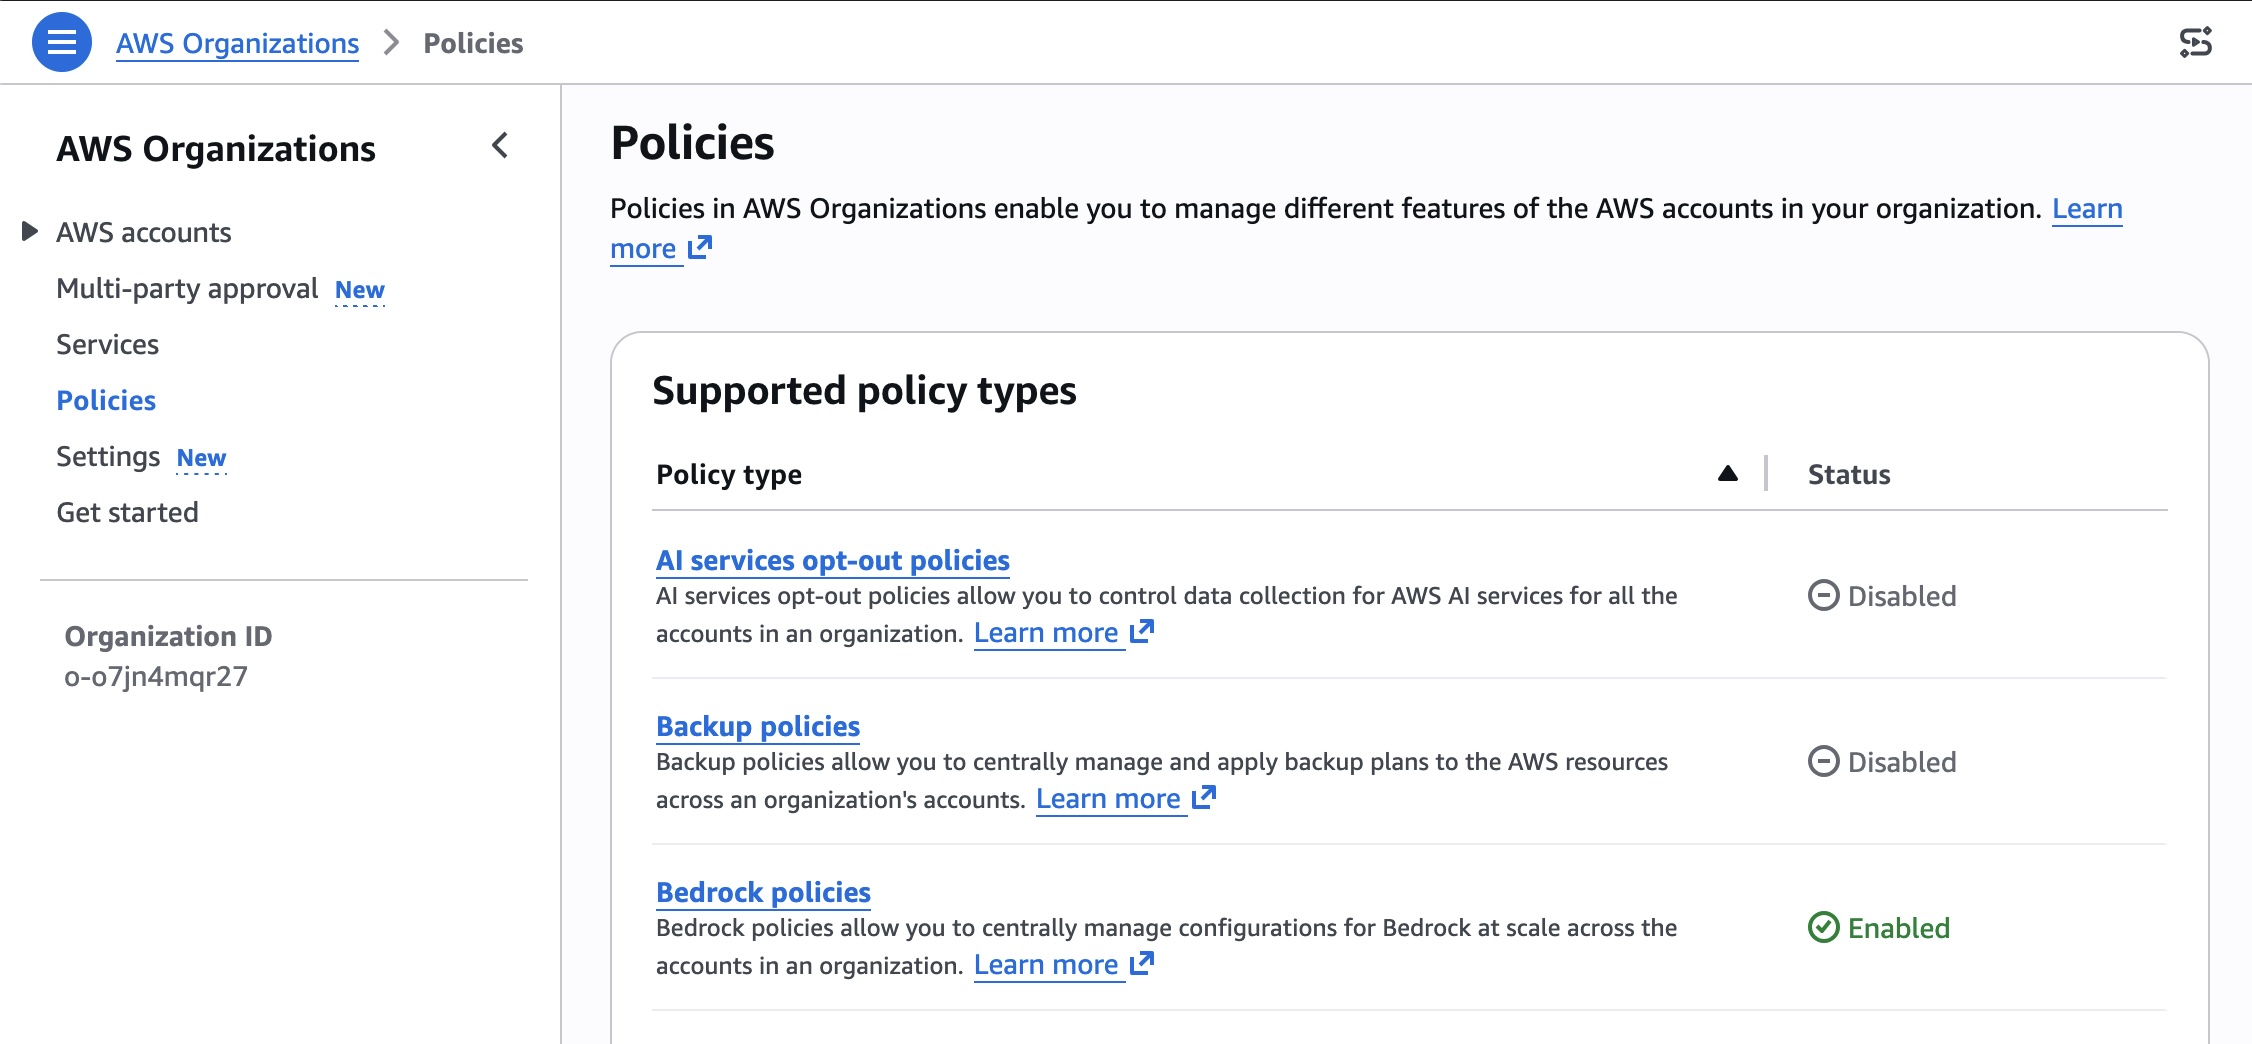
To enable organization-level enforcement, go to AWS Organizations console and choose Policies menu. You can enable the Bedrock policies in the console.
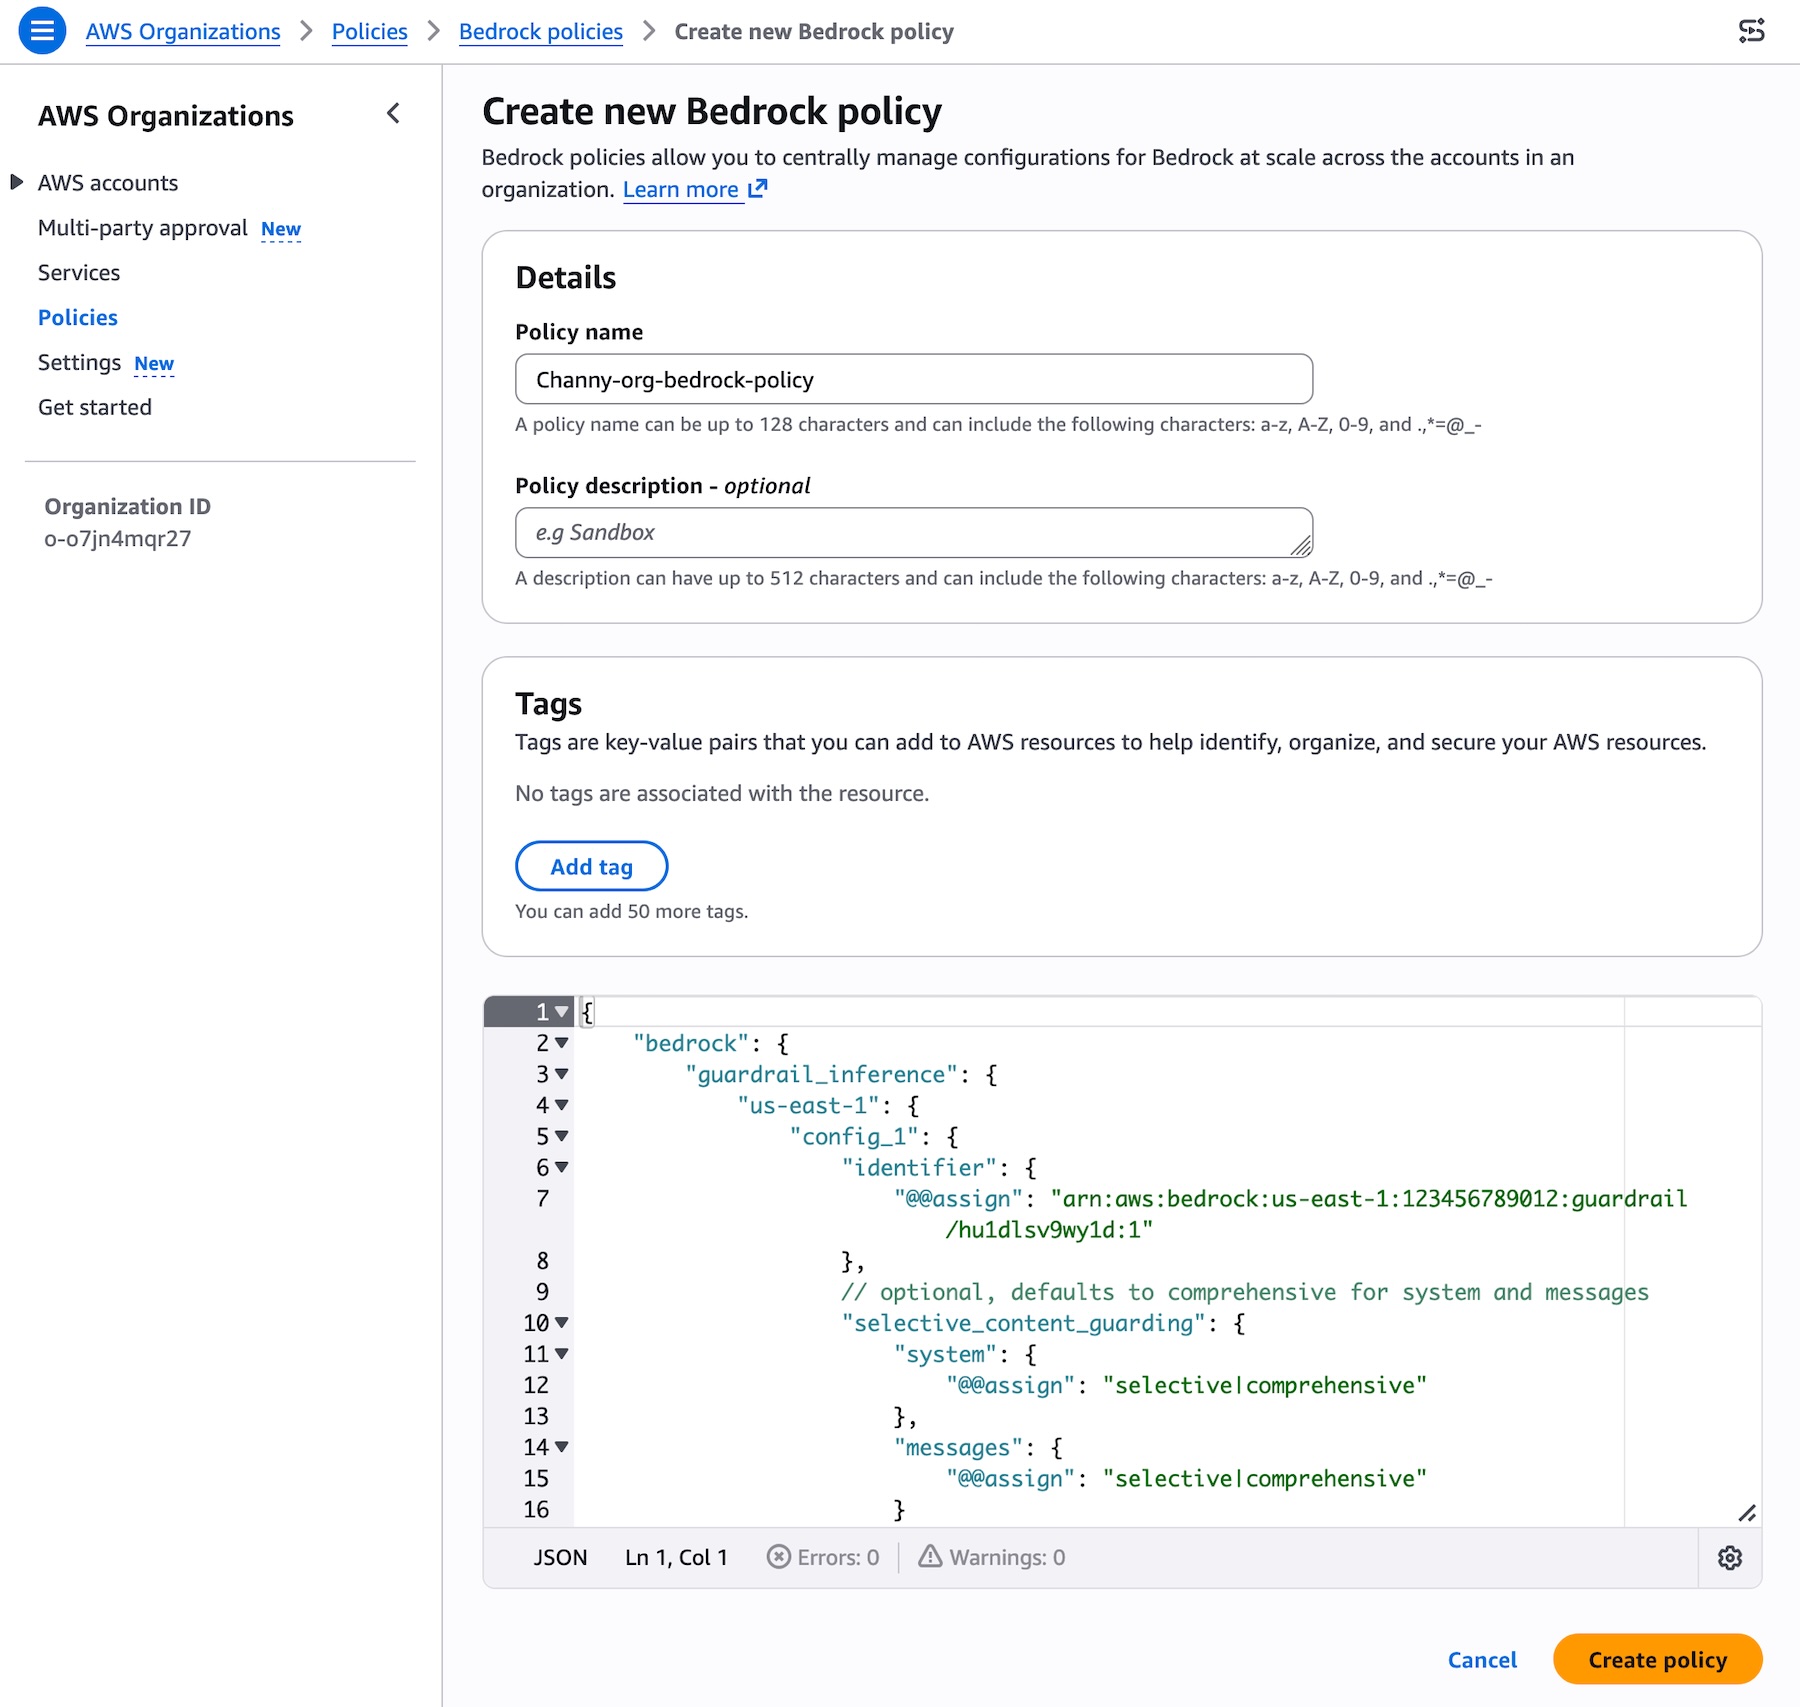
You can create a Bedrock policy that specifies your guardrail and attach it to your target accounts or OUs. Choose Bedrock policies enabled and Create policy. Specify your guardrail ARN and version and configure the input tags setting for in the AWS Organizations. To learn more, visit Amazon Bedrock policies in AWS Organizations and Amazon Bedrock policy syntax and examples.
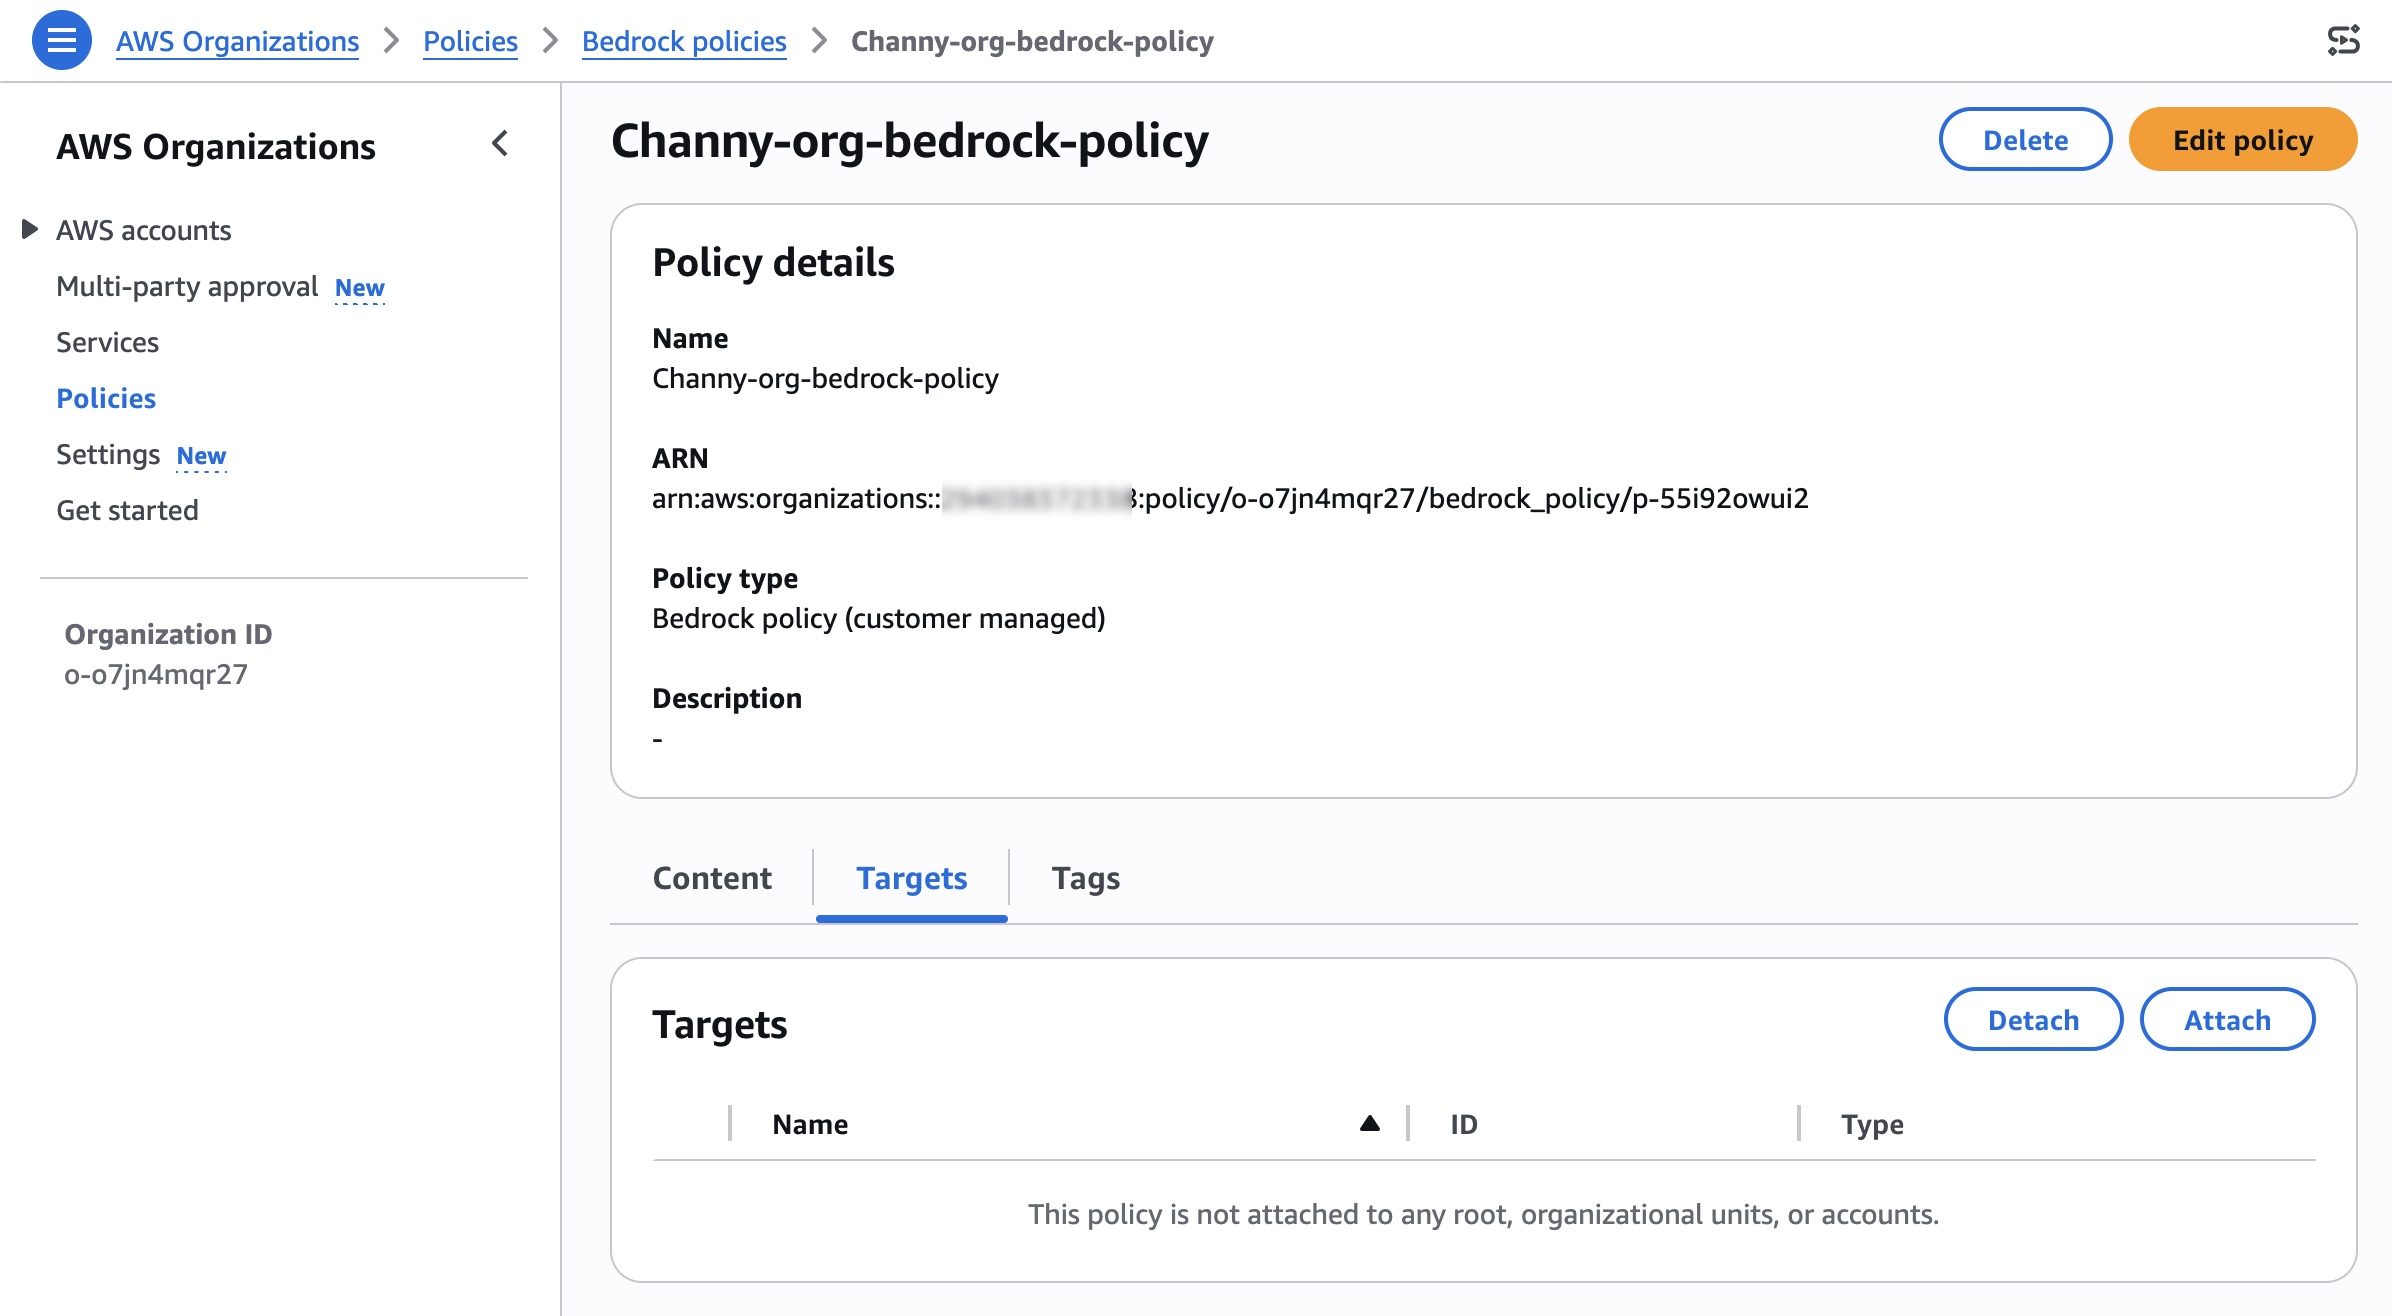
After creating the policy, you can attach the policy to your desired organizational units, accounts, root in the Targets tab.
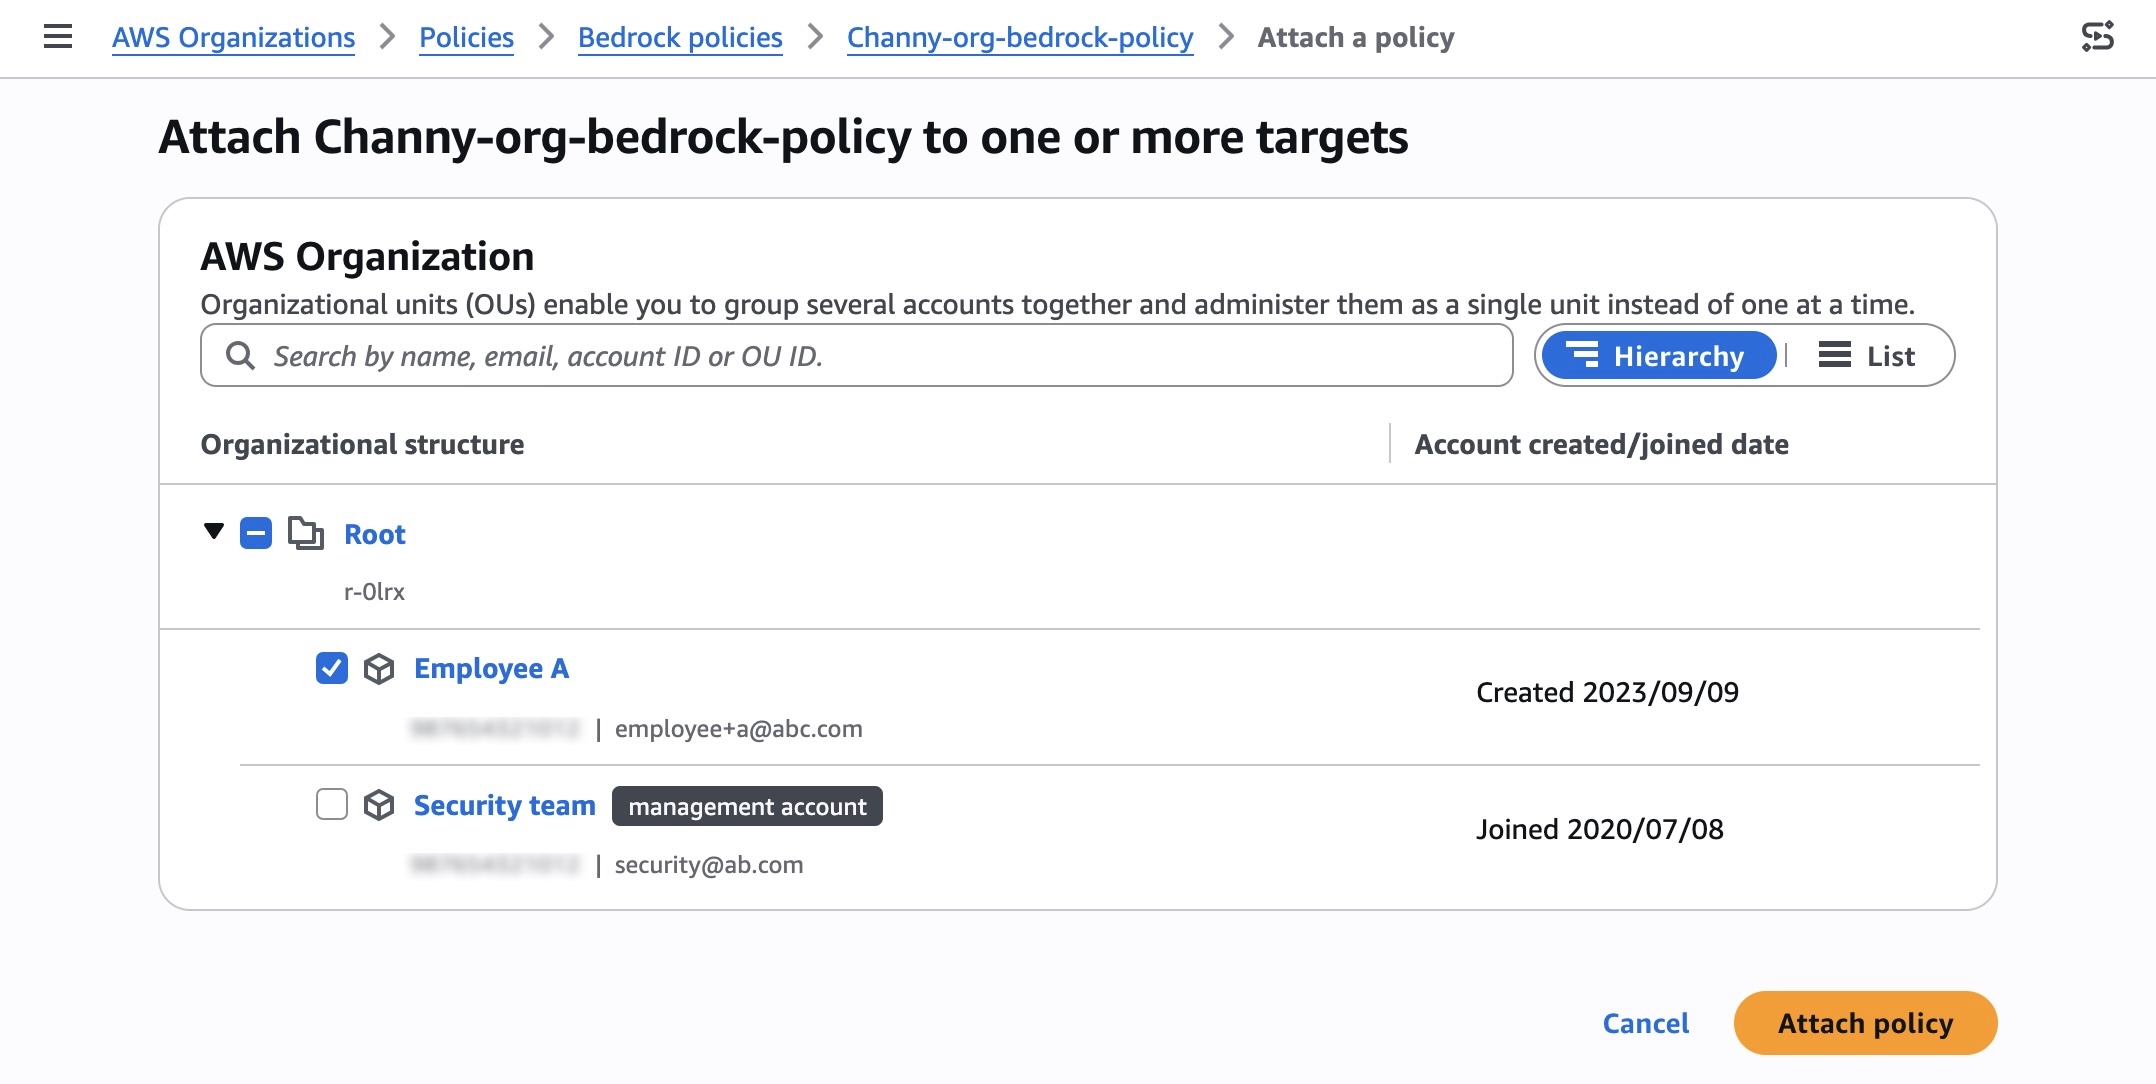
Search and select your organization root, OUs, or individual accounts to attach your policy, and choose Attach policy.
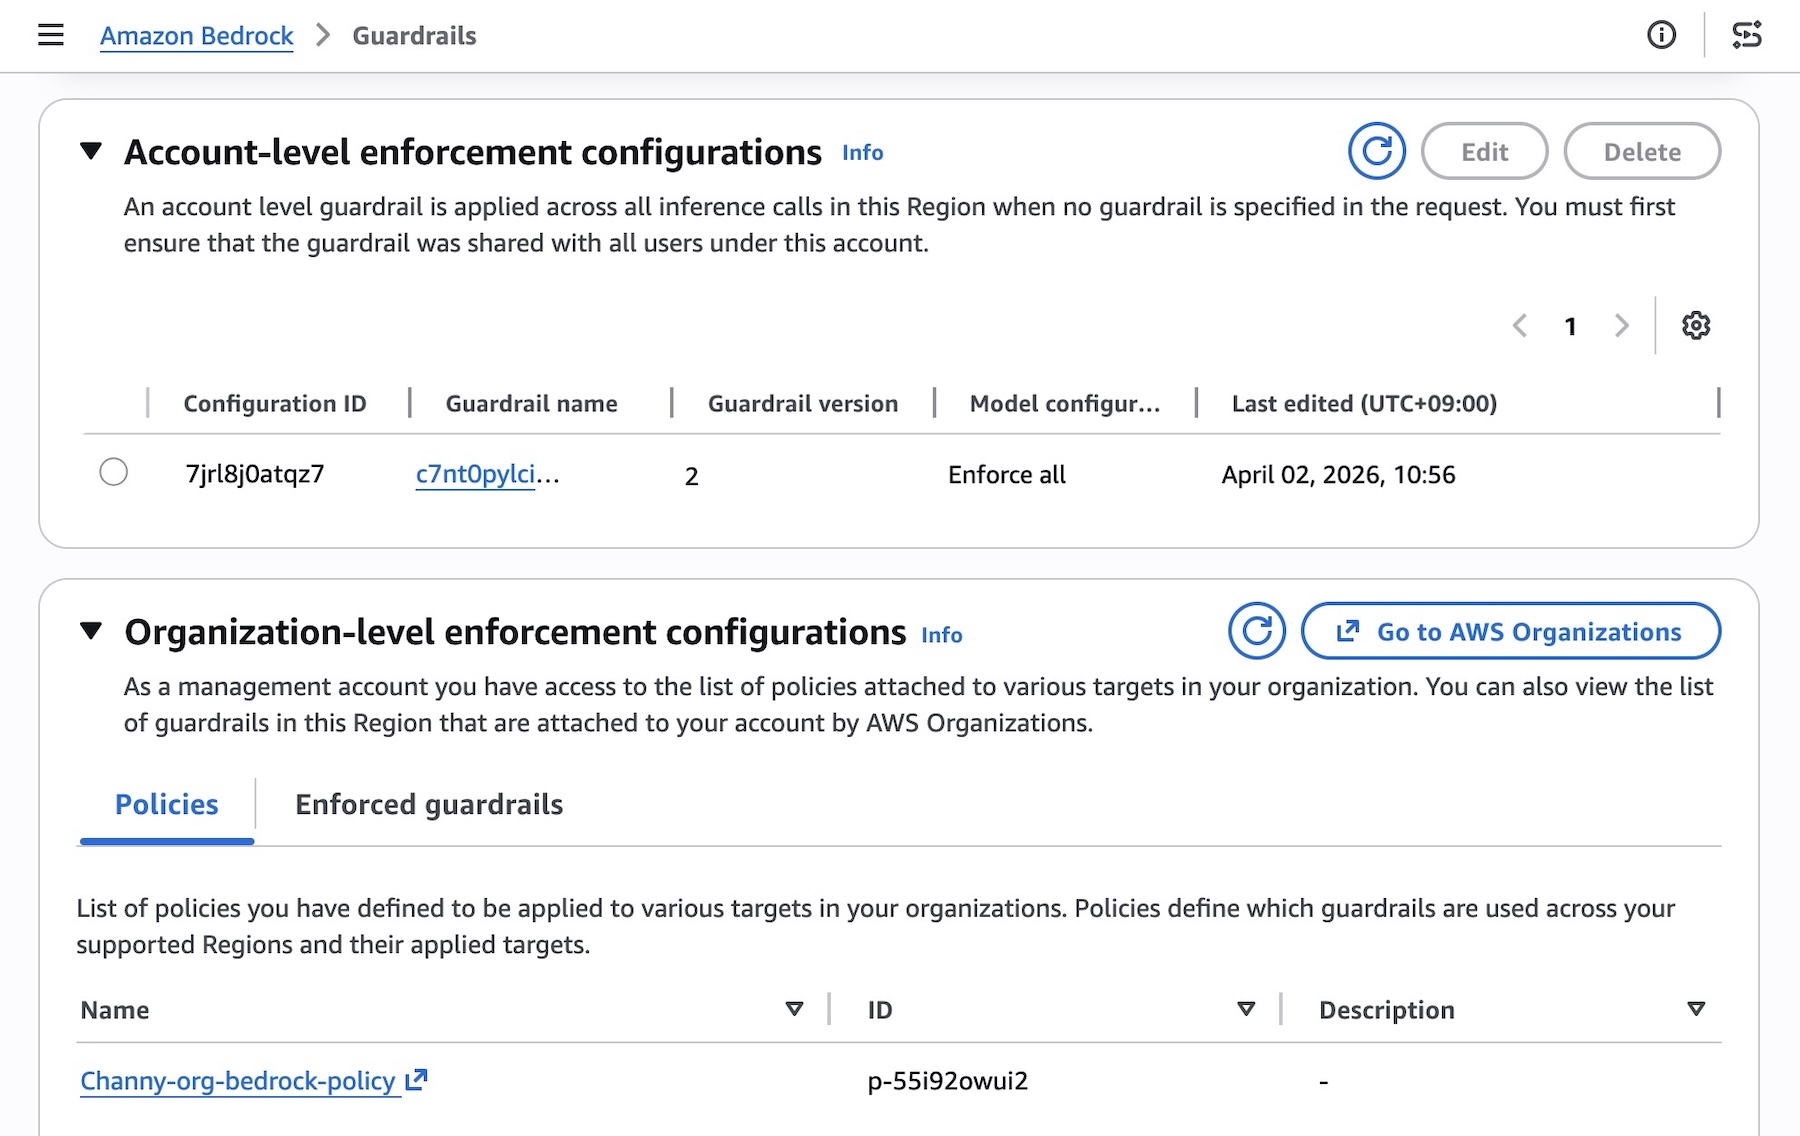
You can test that the guardrail is being enforced on member accounts and verify which guardrail is enforced. From a member account attached, you should see the organization enforced guardrail under the section Organization-level enforcement configurations.
The underlying safeguards within the specified guardrail are then automatically enforced for every model inference request across all member entities, ensuring consistent safety controls. To accommodate varying requirements of individual teams or applications, you can attach different policies with associated guardrails to different member entities through your organization.
Things to know Here are key considerations to know about GA features:
You can now choose to include or exclude specific models in Bedrock for inference, enabling centralized enforcement on model invocation calls. You can also choose to safeguard partial or complete system prompts and input prompts. To learn more, visit Apply cross-account safeguards with Amazon Bedrock Guardrails enforcement.
Ensure you are specifying the accurate guardrail Amazon Resource Names (ARN) in the policy. Specifying an incorrect or invalid ARN will result in policy violations, non-enforcement of safeguards, and the inability to use the models in Amazon Bedrock for inference. To learn more, visit Best practices for using Amazon Bedrock policies.
Automated Reasoning checks are not supported with this capability.
Now available Cross-account safeguards in Amazon Bedrock Guardrails is generally available today in the all AWS commercial and GovCloud Regions where Bedrock Guardrails is available. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. Charges apply to each enforced guardrail according to its configured safeguards. For detailed pricing information on individual safeguards, visit Amazon Bedrock Pricing page.
This week, we added a whole new bunch of HTTP/HTTPS-based CMD payloads for X64 and X86 versions of Windows. The additional breadth of selectable payloads and delivery techniques allows users new options to tailor the attack workflow for their environment. This was contributed by bwatters-r7. Adding new architectures for adapted payloads is surprisingly easy and something a first-time contributor might want to look into!
New modules added to Metasploit Framework also allow for targeting FreeScout and Grav CMS, both of which result in remote code execution. These modules were contributed by Chocapikk and x1o3 respectively. Thanks!
Thanks to g0tmi1k, Metasploit Framework now also includes an exploit module, multi/http/os_cmd_exec, which allows for targeting generic HTTP command execution vulnerabilities where user-supplied input is directly passed to system execution functions via an HTTP request. This can result in a Meterpreter shell on the remote target.
To round this week off, we have a new persistence technique on Windows, thanks to Nayeraneru, which abuses the HKCU\Environment\UserInitMprLogonScript registry value to execute a payload at user logon.
New module content (5)
FreeScout Unauthenticated RCE via ZWSP .htaccess Bypass
Description: This adds an exploit module for CVE-2026-28289, an unauthenticated remote code execution vulnerability in FreeScout versions prior or equal to 1.8.206.
Grav CMS Admin Direct Install Authenticated Plugin Upload RCE
Description: This adds a new exploit module for CVE-2025-50286, an authenticated RCE vulnerability in Grav CMS 1.1.x–1.7.x with Admin Plugin 1.2.x–1.10.x. The module exploits the Direct Install feature to upload a malicious plugin ZIP and execute an arbitrary PHP payload as the web server user.
Description: Adds a new exploits/multi/http/os_cmd_exec module that targets generic HTTP command execution vulnerabilities where user-supplied input is directly passed to system execution functions via an HTTP request.
Description: This adds a new Windows persistence module that abuses the HKCU\Environment\UserInitMprLogonScript registry value to execute a payload at user logon.
Description: This adds HTTP and HTTPS fetch payloads for 32-bit Windows targets.
Enhancements and features (8)
#20999 from Aaditya1273 – Removes the legacy windows/local/persistence module, which has been superseded by the modernized windows/persistence/registry module. A moved_from alias ensures that existing scripts and workflows referencing the old module path are automatically redirected to the new one with a deprecation warning.
#21090 from g0tmi1k – Updates multiple modules to make use of report_service().
#21097 from g0tmi1k – Updates auxiliary/scanner/ftp/anonymous.rb to report the FTP service regardless of anonymous being enabled.
#21144 from Nayeraneru – Improves YARD documentation for lib/msf/core/auxiliary/web/http.rb by documenting the Request and Response helpers, the public HTTP request APIs, and the internal custom-404/request-handling flow.
#21145 from Nayeraneru – Adds YARD docs to lib/msf/core/auxiliary/auth_brute.rb, focusing on the AuthBrute mixin’s credential-building, brute-force state, logging, and cleanup helpers.
#21150 from Nayeraneru – Adds YARD documentation to lib/msf/core/payload/adapter/fetch.rb to improve consistency and clarify how the fetch adapter generates URIs, builds fetch commands, and resolves platform-specific execution behavior.
#21194 from bcoles – This updates the post/linux/gather/enum_protections module by adding documentation and additional checks for modern protections and applications.
#21214 from adfoster-r7 – Adds additional validation to db_import before attempting to import values.
#21048 from zeroSteiner – Not written – add release notes directly to the pull request, then regenerate. Do not edit manually without ensuring the pull request has the release note present.
Bugs fixed (6)
#21004 from EclipseAditya – This fixes a bug in the #normalize_key method provided by the Windows Registry mixin. The result is correct behavior when using shell sessions to check for keys with trailing \ characters.
#21138 from g0tmi1k – Fixes a bug that stopped the auxiliary/server/dhcp module from running as a background job when RHOSTS had been set.
#21188 from adfoster-r7 – Fixes a crash on older Ruby versions when scanning binary files.
#21199 from Hemang360 – Fixes crash in auxiliary/scanner/http/wp_perfect_survey_sqli when run against invalid or unreachable targets.
#21207 from zeroSteiner – Fixes warning when running the linux/gather/enum_protections module.
#21208 from adfoster-r7 – Fixes multiple warnings in modules that reported notes incorrectly.
#21073 from Hemang360 – Fixes a bug where running exploit/multi/handler with a reverse HTTP/HTTPS payload multiple times on the same port caused cleanup issues.
Documentation added (6)
#21149 from Adithyadspawar – Adds documentation to the following login scanners: ftp/bison_ftp_traversal, http/apache_activemq_traversal, http/coldfusion_version, http/drupal_views_user_enum and http/elasticsearch_traversal.
#21186 from Devansh7006 – Adds documentation for the wordpress_pingback_access module.
#21187 from Devansh7006 – Updates documentation for auxiliary/scanner/http/http_put.
#21200 from dineshg0pal – Updates the example code snippet for writing Metasploit Go modules.
#21201 from aryan9190 – Adds YARD documentation for Rex::Post::IO class.
#21217 from dineshg0pal – Fixes minor errors in documentation files.
You can always find more documentation on our docsite at docs.metasploit.com.
Get it
As always, you can update to the latest Metasploit Framework with msfupdate and you can get more details on the changes since the last blog post from GitHub:
This is a guest post written by Jasdeep Singh Bhalla from GoDaddy.
AWS Cloud Development Kit (CDK) Aspects are a powerful mechanism that allows you to apply organization-wide policies, like security rules, tagging standards, and compliance requirements across your entire infrastructure as code. By implementing the Visitor pattern, Aspects can inspect and modify every construct in your CDK application before it’s synthesized into AWS CloudFormation templates, enabling you to enforce organizational standards automatically at build time.
At GoDaddy, we’ve used CDK Aspects to transform how we enforce compliance across our massive AWS footprint. Our Cloud Governance team is responsible for ensuring every AWS resource deployed across thousands of accounts adheres to strict security, compliance, and operational standards.
We have a simple goal:
Make it easy for developers to do the right thing without slowing them down.
Traditionally, we relied on documentation, Slack threads, and peer reviews to flag misconfigurations. But as our cloud footprint grew, this approach quickly hit its limits. It simply didn’t scale.
We needed something proactive.
From reactive to proactive: CloudFormation Hooks
Our first major leap forward came through CloudFormation Hooks. These allow us to validate every resource in a CloudFormation template against our compliance rules at deployment time. If a resource passes, it gets deployed. If not, the deployment is blocked, and we provide developers with clear, actionable error messages to help them fix the template.
This worked well, but it wasn’t perfect. Developers would often only discover issues after writing their entire templates using manual values to make the template compliant, and attempting deployment. This was a time-consuming process, and it was not a good developer experience.
We needed an automated way to make CloudFormation templates compliant with our compliance rules without manual effort.
CDK Aspects are our answer to proactive, early-stage compliance enforcement — catching and resolving issues at the code level, before deployment.
In AWS CDK, an Aspect is a lightweight Visitor that can inspect and act on every construct in your infrastructure code before it’s synthesized into a CloudFormation template. This means you can apply organization-wide rules as developers write CDK code, not after.
Think of it as linting for your infrastructure.
Want to ensure all Amazon Simple Storage Service (Amazon S3) buckets have encryption enabled? Require specific tags on resources? Block public access on security groups? With CDK Aspects, all of that becomes not only possible, but automatic.
Under the hood: how CDK Aspects work
CDK Aspects are a powerful mechanism for inspecting and modifying your infrastructure as code. At their core, they use the Visitor Pattern, which allows you to traverse a tree of objects (constructs) and perform operations on each node without modifying the constructs themselves directly.
Interface IAspect
An Aspect is a class that implements the IAspect interface:
The single visit() method is called for every construct in the scope where the Aspect is applied. Inside visit(), you can inspect, modify, or enforce rules on the construct.
Adding Aspects
To attach an Aspect to a construct (or a tree of constructs), use the following method:
Aspects.of(myConstruct).add(new SomeAspect());
This adds the Aspect to the construct’s internal list.
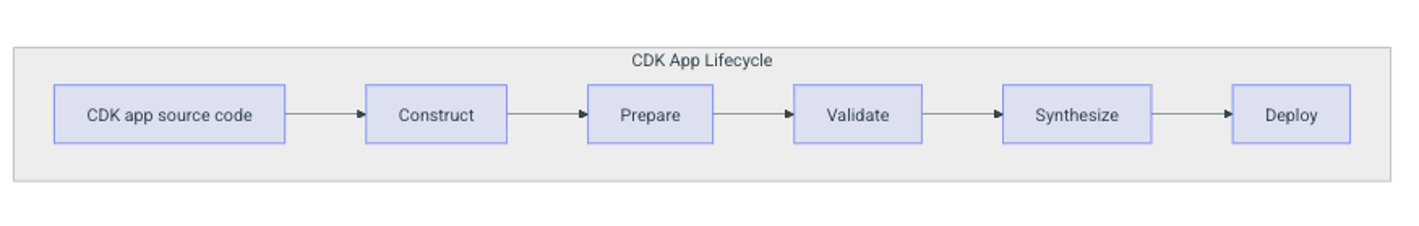
When cdk deploy is run, a CDK app goes through several phases:
Figure 1: CDK app lifecycle from source code to deployment
Construction – Constructs are instantiated.
Preparation – Final modifications and Aspects are applied.
Validation – Checks for invalid configurations.
Synthesis – CloudFormation templates are generated.
Deployment – Resources are provisioned in AWS.
Aspects are executed during the Preparation phase, which happens automatically. This ensures all rules, validations, or mutations are applied before synthesis, so your generated CloudFormation templates are compliant and valid before deployment.
During the Preparation phase of the CDK lifecycle, CDK traverses the construct tree and calls visit() on each node in top-down order (parent → children). Inside visit(), you can inspect, modify, or enforce rules on the construct.
visit(node: IConstruct) {
    if (node instanceof s3.Bucket) {
        node.encryption = s3.BucketEncryption.KMS; // Mutates the resource
    }
}
Example: CDK Aspects to automatically add S3 Encryption to all S3 buckets in a stack by mutating the resource.
class EnforceBucketEncryption implements IAspect {
    visit(node: IConstruct) {
        if (node instanceof s3.Bucket) {
            node.encryption = s3.BucketEncryption.KMS; // Mutates the resource
        }
    }
}
This aspect can be registered on the stack by calling the following method:
From the example above, you can see that the BucketEncryption property is added to the MyBucket resource by the Aspect.
During the prepare phase, CDK traverses the construct tree from top to bottom – starting at the App, then each Stack, and down to resources like S3 buckets. At each node, Aspects are applied by invoking aspect.visit(node), allowing inspection and modification of resources. By the time CDK reaches the synth step, the CloudFormation template already includes these Aspect-driven changes, ensuring compliance and best practices are consistently enforced before deployment.
Types of CDK Aspects
AWS CDK distinguishes between two types of Aspects based on how they interact with your infrastructure: those that modify resources (mutating) and those that only inspect them (read-only).
Mutating Aspects
Mutating Aspects modify resources automatically (like adding encryption or logging). These change the properties of resources as they traverse your constructs. They are ideal for enforcing compliance and best practices like:
Mutating Aspects are powerful, but overusing them can introduce unintended changes, because they modify resources without explicit developer action.Always make sure you are aware of the changes, and avoid applying them to production resources without caution. Use logging or annotations to help you understand and debug the changes.
For example, the following aspect sets the default timeout on all Lambda functions to 300 seconds:
class SetDefaultTimeouts implements IAspect {
    visit(node: IConstruct) {
        if (node instanceof lambda.Function) {
            node.timeout = 300; // mutates the resource
        }
    }
}
Read-only Aspects
Read-only Aspects only inspect resources and report findings without modifying them. They’re ideal for compliance checks, tagging audits, and policy validation.
At GoDaddy, we use mutating Aspects to enforce compliance automatically, reducing manual work and ensuring stacks are compliant with our standards by default. We add read-only Aspects for stricter audits where mutation isn’t appropriate.
Common use cases for CDK Aspects
When building cloud infrastructure at scale, enforcing consistency across stacks can be an ongoing challenge. AWS CDK Aspects let you automatically enforce security, compliance, and operational standards across your entire infrastructure.
Below are some of the most impactful use cases where Aspects can save you time, reduce risk, and improve governance.
Security & compliance: Security and compliance go hand in hand, and Aspects are a powerful way to enforce both before resources ever reach AWS. With Aspects, you can:
Validate that required tags (like cost allocation tags) are present
IAM policies: Aspects make it trivial and consistent across all stacks to apply the same permissions boundary to every IAM role.
Tagging enforcement: Tags are the backbone of cost allocation, compliance, and automation. Yet, they’re easy to forget. With Aspects, you can enforce required tags across every resource.
Operational best practices: Use Aspects to enforce sensible defaults and operational hygiene:
Testing made easier: You can use Aspects to override the default RemovalPolicy for test stacks to DESTROY, ensuring everything is cleaned up automatically.
Working around 3rd-party constructs: Sometimes external constructs create resources you can’t fully configure, like an S3 bucket without encryption or logging options. Instead of waiting on maintainers or forking the library, you can apply an Aspect to modify those resources directly.
Network policies: Networking issues often lead to security incidents. With Aspects, you can:
Cost control: Budgets matter. Aspects can help by:
Flagging high-cost instance types before deployment
Limiting use of expensive storage classes
Warning when provisioned throughput exceeds thresholds
You can combine these use cases into reusable, testable policies that run consistently across all CDK stacks.
CDK Aspects in action at GoDaddy
At GoDaddy, we define CDK Aspects and distribute them through a wrapper Stack that development teams use when building infrastructure with CDK. Every template a team creates is automatically made compliant with GoDaddy’s cloud compliance rules, without requiring manual updates or fixes.
As an example, some of the Aspects are:
S3BucketAspect – Enforces encryption, logging, and public access block on S3 buckets.
IAMRoleAspect – Flags wildcard permissions and enforces naming conventions.
LambdaFunctionAspect – Validates timeouts, memory limits, and Amazon VPC configurations.
These Aspects enforce security, operational, and tagging standards at the code level. When you use the wrapper stack, the relevant Aspects are applied automatically, injecting the necessary properties into the CloudFormation template before deployment. This is intended to support compliance without slowing down development.
Each of these aspects implements the IAspect interface and is applied to stacks directly:
This approach means that when a developer defines a new resource, like an S3 bucket or IAM role, all relevant compliance rules are automatically applied:
const bucket = new s3.Bucket(myStack, "MyBucket", {
    // developer doesn't need to manually configure encryption or logging
});
During the CDK preparation phase, the aspect injects the required properties into the CloudFormation template, which is done before the template is synthesized and deployed. This ensures that the resources are deployed with the required properties at GoDaddy’s standards.
Consider a team that deploys hundreds of S3 buckets per month, where each bucket requires encryption, logging, versioning, and public access block. With CDK Aspects, you don’t have to manually update the CloudFormation template to add the required properties.
This saves a lot of engineering effort and time, and ensures that the resources are deployed with the required properties that meet GoDaddy’s standards.
Conclusion
At GoDaddy, CDK Aspects have significantly transformed our approach to cloud infrastructure compliance.
Because Aspects run during the CDK preparation phase, before synthesis and deployment, they inject required properties like encryption, logging, and access controls into CloudFormation templates automatically. Developers write their CDK code as usual, and compliance happens behind the scenes. This eliminates the manual effort of configuring each resource to meet security and compliance standards.
This proactive approach has also improved developer productivity. Instead of discovering compliance failures after attempting deployment (as was the case with CloudFormation Hooks alone), developers now get compliant templates on the first synthesis. Fewer failed deployments mean faster iteration cycles and less time spent debugging configuration issues.
Policy enforcement is consistent because every team uses the same wrapper Stack with the same Aspects applied. Whether a team deploys an S3 bucket, an IAM role, or a Lambda function, the same tagging, encryption, network isolation, and cost control rules are applied uniformly.
Finally, this model scales. Adding a new compliance rule means updating a single Aspect in the shared library, and every stack that uses the wrapper inherits the change automatically. This lets our Cloud Governance team enforce standards across thousands of accounts with minimal operational overhead.
If you’re working with AWS CDK at scale, adopting CDK Aspects isn’t just a nice-to-have, it’s essential. Your future self and your security team will thank you.
To get started, pick one compliance rule, like S3 encryption, and implement it as a mutating Aspect. Once you see how it works, expand to cover tagging and IAM policies. From there, package your Aspects into a shared library that teams across your organization can adopt.
Pull requests are the beating heart of GitHub. As engineers, this is where we spend a good portion of our time. And at GitHub’s scale—where pull requests can range from tiny one-line fixes to changes spanning thousands of files and millions of lines—the pull request review experience has to stay fast and responsive.
We recently shipped the new React-based experience for the Files changed tab (now the default experience for all users). One of our main goals was to ensure a more performant experience across the board, especially for large pull requests. That meant investing in, and consistently prioritizing, the hard problems like optimized rendering, interaction latency, and memory consumption.
For most users before optimization, the experience was fast and responsive. But when viewing large pull requests, performance would noticeably decline. For example, we observed that in extreme cases, the JavaScript heap could exceed 1 GB, DOM node counts surpassed 400,000, and page interactions became extremely sluggish or even unusable. Interaction to Next Paint (INP) scores (a key metric in determining responsiveness) were above acceptable levels, resulting in an experience where users could quantifiably feel the input lag.
Our recent improvements to the Files changed tab have meaningfully improved some of these core performance metrics. While we covered several of these changes briefly in a recent changelog, we’re going to cover them in more detail here. Read on for why they mattered, what we measured, and how those updates improved responsiveness and memory pressure across the board and especially in large pull requests.
Performance improvements by pull request size and complexity
As we started to investigate and plan our next steps for improving these performance issues, it became clear early on that there wouldn’t be one silver bullet. Techniques that preserve every feature and browser-native behavior can still hit a ceiling at the extreme end. Meanwhile, mitigations designed to keep the worst-case from tipping over can be the wrong tradeoff for everyday reviews.
Instead of looking for a single solution, we began developing a set of strategies. We selected multiple targeted approaches, each designed to address a specific pull request size and complexity.
Those strategies focused on the following themes:
Focused optimizations for diff-line components. Make the primary diff experience efficient for most pull requests. Medium and large reviews stay fast without sacrificing expected behavior, like native find-in-page.
Gracefully degrade with virtualization. Keep the experience usable for the largest pull requests. Prioritize responsiveness and stability by limiting what is rendered at any moment.
Invest in foundational components and rendering improvements. These compound across every pull request size, regardless of which mode a user ends up in.
With these strategies in mind, let’s explore the specific steps we took to address these challenges and how our initial iterations set the stage for the improvements that followed.
First steps: Optimizing diff lines
With our team’s goal of improving pull request performance, we had three main objectives:
Reduce memory and JavaScript heap size.
Reduce the DOM node count.
Reduce our average INP and significantly improve our p95 and p99 measurements
To hit these goals, we focused on simplification: less state, fewer elements, less JavaScript, and fewer React components. Before we look at the results and new architecture, let’s take a step back and look at where we started.
What worked and what didn’t with v1
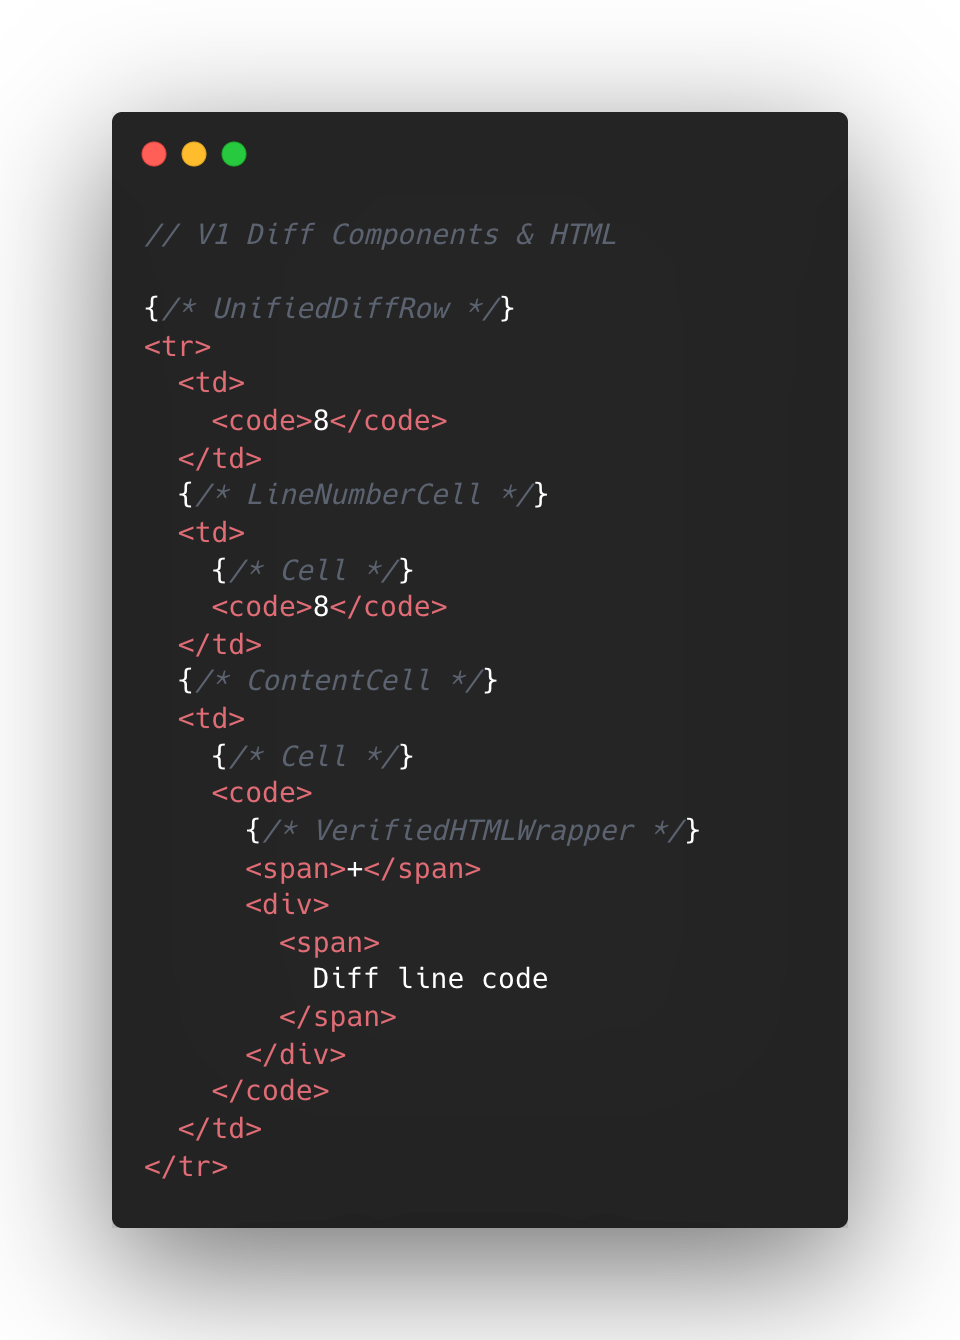
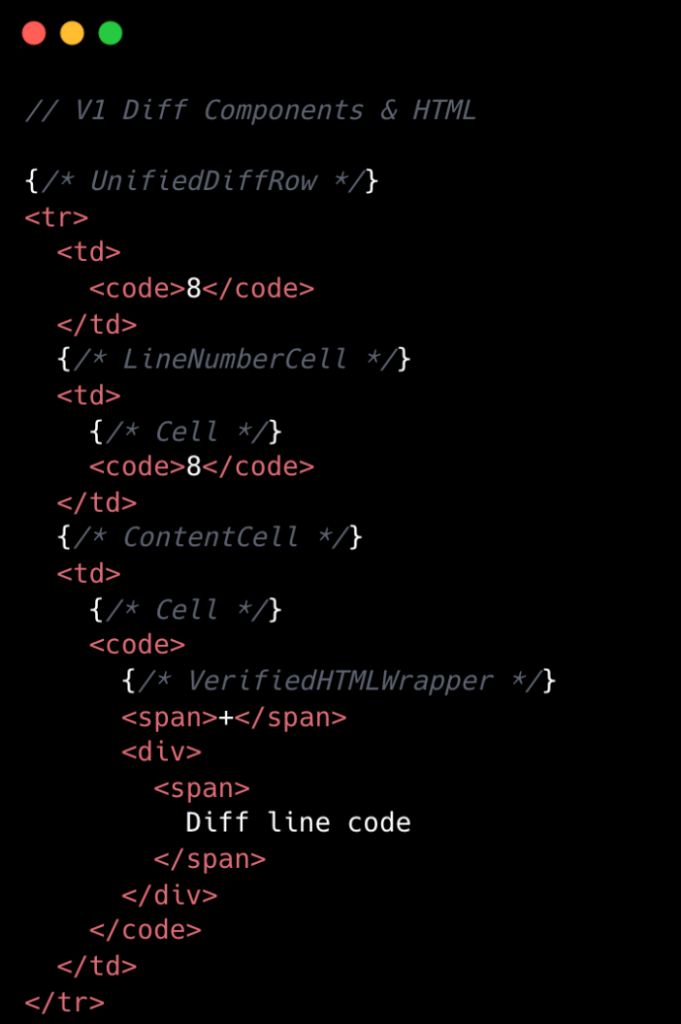
In v1, each diff line was expensive to render. In unified view, a single line required roughly 10 DOM elements; in split view, closer to 15. That’s before syntax highlighting, which adds many more <span> tags and drives the DOM count even higher.
The following is a simplified visual of the React Component structure mixed with the DOM tree elements for v1 diffs.
At the React layer, unified diffs typically contain at least eight components per line, while the split view contain a minimum of 13. And these numbers represent baseline counts; extra UI states like comments, hover, and focus could add more components on top.
This approach made sense to us in v1, when we first ported the diff lines to React from our classic Rails view. Our original plan centered around lots of small reusable React components and maintaining DOM tree structure.
But we also ended up attaching a lot of React event handlers in our small components, often five to six per component. On a small scale, that was fine, but on a large scale that compounded quickly. A single diff line could carry 20+ event handlers multiplied across thousands of lines.
Beyond performance impact, it also increased complexity for developers. This is a familiar scenario where you implement an initial design, only to discover later its limitations when faced with the demands of unbounded data.
To summarize, for every v1 diff line there would be:
Minimum of 10-15 DOM tree elements
Minimum of 8-13 React Components
Minimum of 20 React Event Handlers
Lots of small re-usable React Components
This v1 strategy proved unsustainable for our largest pull requests, as we consistently observed that larger pull request sizes directly led to slower INP and increased JavaScript heap usage. We needed to determine the best path for improving this setup.
Small changes make a large impact: v2
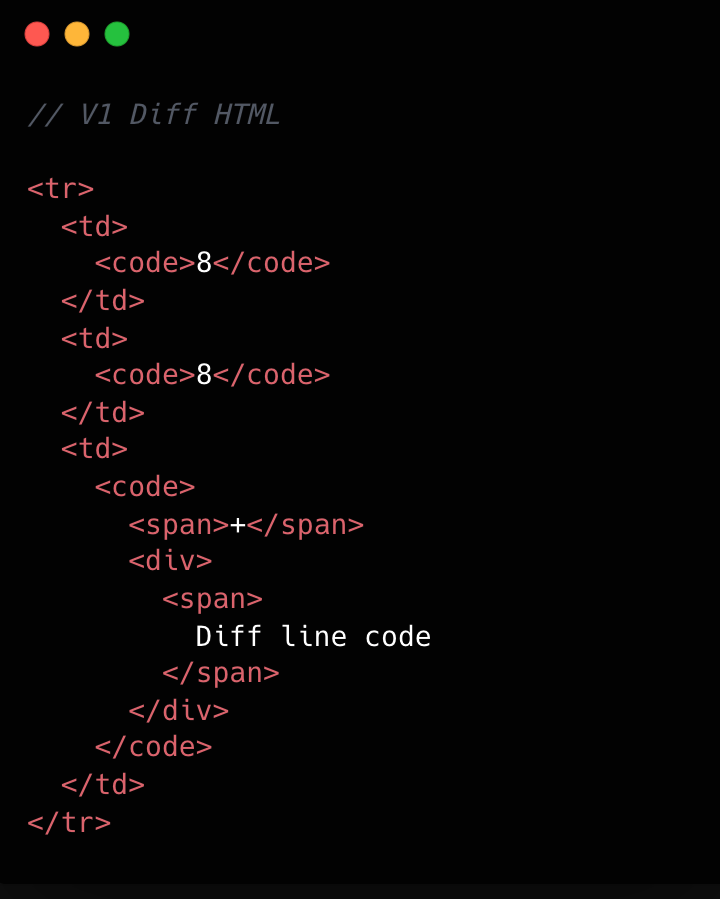
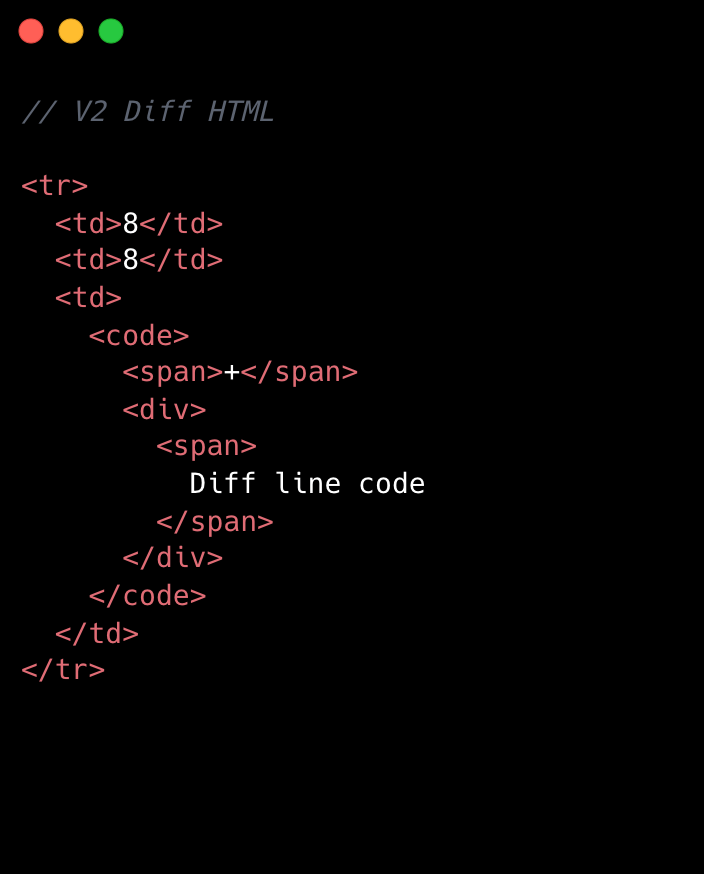
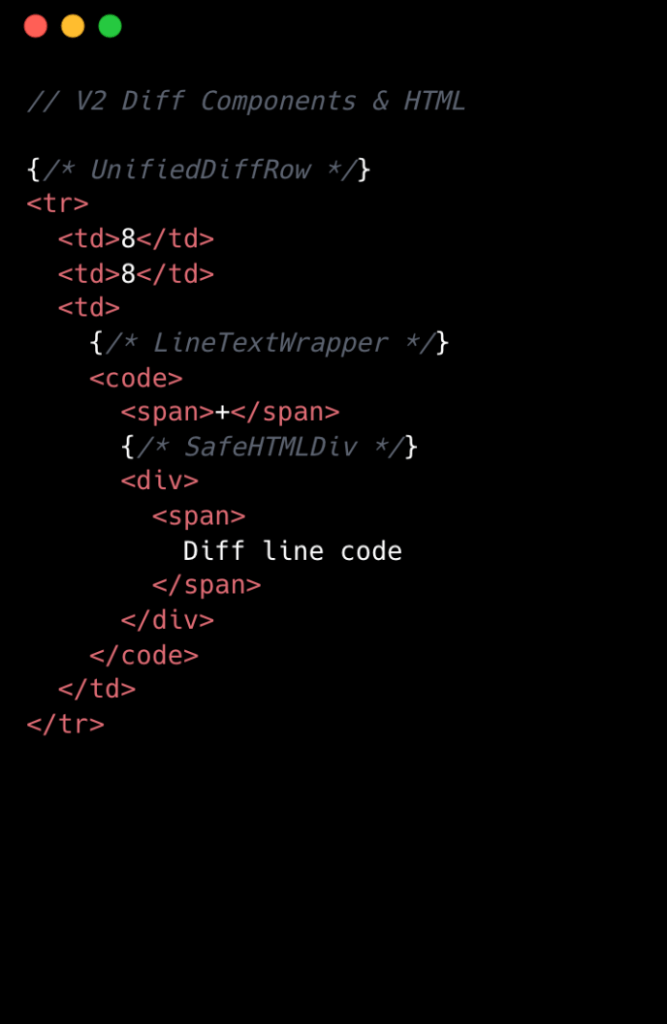
No change is too small when it comes to performance, especially at scale. For example, we removed unnecessary <code> tags from our line number cells. While dropping two DOM nodes per diff line might appear minor, across 10,000 lines, that’s 20,000 fewer nodes in the DOM. These kinds of targeted, incremental optimizations, no matter how small, compound to create a much faster and more efficient experience. By not overlooking these details, we ensured that every opportunity for improvement was captured, amplifying the overall impact on our largest pull requests.
Refer to the images below to see how v1 looks compared to v2.
This becomes clearer if we look at the component structure behind this HTML:
We went from eight components per diff line to two. Most of the v1 components were thin wrappers that let us share code between Split and Unified views. But that abstraction had a cost: each wrapper carried logic for both views, even though only one rendered at a time. In v2, we gave each view its own dedicated component. Some code is duplicated, but the result is simpler and faster.
Simplifying the component tree
For v2, we removed deeply nested component trees, opting for dedicated components for each split and unified diff line. While this led to some code duplication, it simplified data access and reduced complexity.
Event handling is now managed by a single top-level handler using data-attribute values. So, for instance, when you click and drag to select multiple diff lines, the handler checks each event’s data-attribute to determine which lines to highlight, instead of each line having its own mouse enter function. This approach streamlines both code and improves performance.
Moving complex state to conditionally rendered child components
The most impactful change from v1 to v2 was moving app state for commenting and context menus into their respective components. Given GitHub’s scale, where some pull requests exceed thousands of lines of code, it isn’t practical for every line to carry complex commenting state when only a small subset of lines will ever have comments or menus open. By moving the commenting state into the nested components for each diff line, we ensured that the diff-line component’s main responsibility is just rendering code—aligning more closely with the Single Responsibility Principle.
O(1) data access and less “useEffect” hooks
In v1, we gradually accumulated a lot of O(n) lookups across shared data stores and component state. We also introduced extra re-rendering through useEffect hooks scattered throughout the diff-line component tree.
To address this in v2, we adopted a two-part strategy. First, we restricted useEffect usage strictly to the top level of diff files. We also established linting rules to prevent the introduction of useEffect hooks in line-wrapping React components. This approach enables accurate memoization of diff line components and ensures reliable, predictable behavior.
Next, we redesigned our global and diff state machines to utilize O(1) constant time lookups by employing JavaScript Map. This let us build fast, consistent selectors for common operations throughout our codebase, such as line selection and comment management. These changes have enhanced code quality, improved performance, and reduced complexity by maintaining flattened, mapped data structures.
Now, any given diff line simply checks a map by passing the file path and the line number to determine whether or not there are comments on that line. An access might look like: commentsMap[‘path/to/file.tsx’][‘L8’]
Did it work?
Definitely. The page runs faster than it ever did, and JavaScript heap and INP numbers are massively reduced. For a numeric look, check out the results below. These metrics were evaluated on a pull request using a split diff setting with 10,000 line changes in the diff comparison.
Metric
v1
v2
Improvement
Total lines of code
2,800
2,000
27% less
Total unique component types
19
10
47% fewer
Total components rendered
~183,504
~50,004
74% fewer
Total DOM nodes
~200,000
~180,000
10% fewer
Total memory usage
~150-250 MB
~80-120 MB
~50% less
INP on a large pull request using m1 MacBook pro with 4x slowdown:
~450 ms
~100 ms
~78% faster
As you can see, this effort had a massive impact, but the improvements didn’t end there.
Virtualization for our largest pull requests
When you’re working with massive pull requests—p95+ (those with over 10,000 diff lines and surrounding context lines)—the usual performance tricks just don’t cut it. Even the most efficient components will struggle if we try to render tens of thousands of them at once. That’s where window virtualization steps in.
In front-end development, window virtualization is a technique that keeps only the visible portion of a large list or dataset in the DOM at any given time. Instead of loading everything (which would crush memory and slow things to a crawl), it dynamically renders just what you see on screen, and swaps in new elements as you scroll. This approach is like having a moving “window” over your data, so your browser isn’t bogged down by off-screen content.
To make this happen, we integrated TanStack Virtual into our diff view, ensuring that only the visible portion of the diff list is present in the DOM at any time. The impact was huge: we saw a 10X reduction in JavaScript heap usage and DOM nodes for p95+ pull requests. INP fell from 275–700+ milliseconds (ms) to just 40–80 ms for those big pull requests. By only showing what’s needed, the experience is much faster.
Further performance optimizations
To push performance even further, we tackled several major areas across our stack, each delivering meaningful wins for speed and responsiveness. By focusing on trimming unnecessary React re-renders and honing our state management, we cut down wasted computation, making UI updates noticeably faster and interactions smoother.
On the styling front, we swapped out heavy CSS selectors (e.g. :has(...)) and re-engineered drag and resize handling with GPU transforms, eliminating forced layouts and sluggishness and giving users a crisp, efficient interface for complex actions.
We also stepped up our monitoring game with interaction-level INP tracking, diff-size segmentation, and memory tagging, all surfaced in a Datadog dashboard. This continues to give our developers real-time, actionable metrics to spot and squash bottlenecks before they become issues.
On the server side, we optimized rendering to hydrate only visible diff lines. This slashed our time-to-interactive and keeps memory usage in check, ensuring that even huge pull requests feel fast and responsive on load.
Finally, with progressive diff loading and smart background fetches, users are now able to see and interact with content sooner. No more waiting for a massive number of diffs to finish loading.
All together, these targeted optimizations made our UI feel lighter, faster, and ready for anything our users throw at it.
Diff-initely better: The power of streamlined performance
This exciting journey to streamline the diff line architecture yielded substantial improvements in performance, efficiency and maintainability. By reducing unnecessary DOM nodes, simplifying our React component tree, and relocating complex state to conditionally rendered child components, we achieved faster rendering times and lower memory consumption. The adoption of more O(1) data access patterns and stricter rules for state management further optimized performance. This made our UI more responsive (faster INP!) and easier to reason with.
These measurable gains demonstrate that targeted refactoring, even within our large and mature codebase, can deliver meaningful benefits to all users—and that sometimes focusing on small, simple improvements can have the largest impact. To see the performance gains in action, go check out your open pull requests.
If you run high-scale applications that encrypt large volumes of data, you might be concerned about tracking encryption limits and rotating keys. This post explains how AWS Key Management Service (AWS KMS) and the AWS Encryption SDK handle Advanced Encryption Standard in Galois Counter Mode’s (AES-GCM) encryption limits or bounds automatically by using derived key methods so you don’t have to. These methods generate a new derived key Kd from the main key K by using a random nonce. That way, encryption is done with a unique key each time, and K can be used for much longer. Similar derived key modes have been proposed in various schemes recently like (KC-)XAES, DNDK v2, and ia.cr/2020/1153.
Symmetric encryption bounds
Symmetric encryption algorithms encrypt large amounts of data in transit and at rest. Modern ciphers also authenticate data using an authentication tag — these are called Authenticated Encryption with Additional Data (AEAD) ciphers. Examples of AEAD ciphers include AES-GCM and ChaCha20/Poly1305.
AES-GCM is the most widely used encryption algorithm and was standardized by NIST in SP 800-38D. AES-GCM uses a 128- or 256-bit key K and a (usually 96-bit) initialization vector (IV) to encrypt and authenticate a plaintext P. It also authenticates additional authenticated data (AAD). The output is a ciphertext C and an authentication tag T: (C, T) = AES-GCM(K, IV, AAD, P)
At decryption, the recipient decrypts C and verifies the tag T by using K, IV and AAD and produces the original plaintext P (assuming the tag was authenticated successfully).
Encryption invocation limits
When encrypting data, it’s critical that the K, IV tuple does not repeat for the life of the key K. Otherwise, the security properties of AES-GCM are lost. SP 800-38D requires an implementation to have a probability of key and IV reuse less than one in 4.29 billion (<2-32). This can be achieved by using a deterministic IV that doesn’t repeat or a random IV. If a random IV is used, then it is necessary to rekey after 2-32 encryptions. For example, common protocols like TLS or IKEv2/IPsec prevent (K, IV) collisions by using deterministic (that is, starting from a random value and incrementing) IVs per connection.
Data bounds
Assuming the probability of an (K, IV) collision is statistically insignificant (<2-32), there are still data bounds when encrypting large amounts of plaintexts with the same key K. The block counter in AES-GCM is 32-bits, which leads to a limit of 232-2 bytes (68.72 GB) per encryption operation (per (K, IV) pair). Additionally, a failure to restrict the total amount of data reduces the security guarantees an adversary can distinguish between two different plaintexts, that is knowing which of two messages are encrypted in the ciphertext. The higher protection of indistinguishability, the lower the total number of bytes you can encrypt. NIST’s specification, SP 800-38D, suggests a limit of 268 bytes protected under a single key K which provides an indistinguishability probability of 50%. More conservative security margins are sometimes used, based on different analyses (ia.cr/2024/051, 10.1145/3243734.3243816). AWS sets a more conservative margin too, enforcing a negligible indistinguishability probability (<2-32) by default.
Once you reach the AES-GCM data bounds for a given security margin, you need to rotate the symmetric key. Such limits (for example, 232 encryptions per key with random IVs, or encrypting the maximum total data per key) could be reached in modern, high-scale encryption use cases. Tracking these limits across distributed systems with many concurrent sessions adds operational complexity. We have shared these challenges with using AES-GCM at the scale of AWS in a writeup and a presentation in NIST’s third NIST Workshop on Block Cipher Modes of Operation in 2023.
How AWS KMS uses derived keys
AWS KMS is a managed service that you can use to create and control the keys used to encrypt and sign data. The AWS KMS Encrypt API supports symmetric and asymmetric encryption. For symmetric key encryption, AWS KMS uses AES-GCM with 256-bit keys to encrypt a plaintext up to 4 KB in size. The AWS KMS request includes the plaintext, and the symmetric key identifier (KeyId) of the symmetric customer managed key (CMK) stored in KMS.
A symmetric key Encrypt API call to AWS KMS uses the CMK to derive a symmetric encryption key before encrypting the plaintext. AWS KMS generates a random 128-bit nonce N and produces a 256-bit symmetric key from the main key K specified in the KeyId by using a key derivation function (KDF). A KDF takes in a key, a label and context, an invocation-specific nonce N, and an output length LKm in bytes, and produces key material of that length as Kmat = KDF(K, <label>, <context>, N, LKm). <label> is usually an application- or invocation-specific value. <context> includes invocation-specific input. For AWS KMS, the KDF function is a NIST SP 800-108r1 Counter Mode KDF producing 256 bits of keying material with HMAC-SHA256 as the pseudorandom function. Kd is essentially produced with one call to HMAC-SHA256 with key K as: Kd = HMAC-SHA256(K, <ctx>), where <ctx> consists of a counter value concatenated with constants and N.
Subsequently, AWS KMS generates a 96-bit random IV and encrypts the input plaintext input P with AES-GCM as (C, T) = AES-GCM(Kd, IV, AAD, P).
AWS KMS returns a CiphertextBlob that includes the IV, nonce N, ciphertext and tag (C,T) so that the CiphertextBlob can be decrypted on subsequent calls to the Decrypt API.
Intuitively, the 128-bit random nonce used to derive a per encryption key under a CMK ensures that a caller can go way over the 232 limit on the number of encryptions they can make under the CMK. Furthermore, the limit of 4 KB on the payload size for an AWS Encrypt call ensures the total amount of data encrypted under an encryption key stays well below NIST or other more conservative total encryption bounds. For more details and the mathematics of the security underpinnings of this scheme, see Key Management Systems at the Cloud Scale.
How AWS Encryption SDK applies derived key modes per invocation
The AWS Encryption SDK is a client-side encryption library used for encrypting and decrypting data. It can be configured to use data key caching to reduce API calls when encrypting multiple payloads. Using a nonce-based derived key for each AES-GCM encryption invocation eliminates the need for customers to keep track of the total amount of data they encrypt under a single data key.
Although the AWS Encryption SDK provides a lot of flexibility to accommodate many encryption scenarios, the default configuration handles key derivation and frame sizing automatically, so you don’t need to tune these settings for most use cases. To derive a different key per invocation, like AWS KMS, it uses a randomly generated value, N, the main key K, and some invocation-specific context in the KDF. N is 256 bits in the default configuration. The underlying KDF is the HMAC-based Extract-and-Expand Key Derivation Function (HKDF) with SHA512 as the default hash. Kd is essentially produced with one HKDF call with key K as: Kd = HKDF(K, salt=<lbl>, info=<ctx>, 32), where <lbl> is a constant and <ctx> consists of constants concatenated with a random 256-bit value in the default configuration.
Subsequently, the AWS Encryption SDK uses the derived key Kd to encrypt user content, broken into 4-KB frames by default. Each frame plaintext Pf is encrypted with AES-GCM with a deterministic IV as (C, T) = AES-GCM(Kd, IV, AAD, Pf).
The 96-bit deterministic IV consists of the frame counter frameID, where frameID<232. The additional authenticated data AAD is specific to the Encryption SDK data frame. At decryption, the recipient derives Kd from K in the same way and decrypts the ciphertext C to produce the frame plaintext Pf and validates the authentication tag T.
The 4 KB frame size ensures that by default no more than 244 bytes (232 frames of 4 K bytes each) of data can be encrypted under a single encryption key. This is well below the NIST suggested bound (268), even with data key caching. It is also well below our conservative requirement of <2-32 indistinguishability probability. The limit of invocations per key, even with data key caching, exceeds the encryption counts in most high-scale applications.
Note: While the AWS Encryption SDK makes conservative choices in its default configuration, if you’re using legacy version 1.0 or making configuration changes, you might have lower security guarantees. For example, a custom maximized frame size of 232-1 bytes would lead to larger total plaintext size which is still below the 268 NIST suggested limit, but not below other conservative bounds.
Note that the default AWS Encryption SDK configuration also provides lesser-known security properties, like key commitment. The commitment string is produced similarly to the derived key, by using K and HKDF.
Conclusion
By deriving a unique key per encryption call, AWS KMS and the AWS Encryption SDK eliminate the need to manually track AES-GCM limits.
GNU GRUB 2, mostly just
referred to as GRUB these days, is the most widely used boot loader
for x86_64 Linux systems. It supports reading
from a vast selection of filesystems, handles booting modern systems
with UEFI or legacy systems with a BIOS, and even allows users to customize the
“splash” image displayed when a system boots. Alas, all of those features come with
a price; GRUB has had a parade
of security vulnerabilities over the years. To mitigate some of those
problems, Ubuntu
core developer and Canonical employee Julian Andres Klode has proposed removing
a number of features from GRUB in Ubuntu 26.10 to improve GRUB’s
security profile. His proposal has not been met with universal acclaim; many of the
features Klode would like to remove have vocal proponents.
On April 1, the Gentoo Linux project published a blog post
announcing that it was switching to GNU Hurd as its primary
kernel as an April Fool’s joke. While that is not true, the project
has followed up with an announcement
of a new Gentoo port to the Hurd:
Our crack team has been working hard to port Gentoo to the Hurd and
can now share that they’ve succeeded, though it remains still in a
heavily experimental stage. You can try Gentoo GNU/Hurd using a
pre-prepared disk image. The easiest way to do this is with QEMU
[…]
We have developed scripts to build this image locally and
conveniently work on further development of the Hurd port. Release
media like stages and automated image builds are future goals, as is
feature parity on x86-64. Further contributions are welcome,
encouraged, and needed. Be patient, expect to get your hands dirty,
anticipate breakage, and have fun!
Oh, and Gentoo GNU/Hurd also works on real hardware!
Text for the April Fool’s post is available at the bottom of the
real announcement.
This article explains why many breaches are driven by gaps in visibility rather than advanced exploits, how attackers move through modern environments, and what changes when organizations start connecting assets, identities, and attack paths into a single view.
What is a visibility problem in cybersecurity?
A visibility problem exists when security teams cannot clearly answer three basic questions: what assets exist, who or what can access them, and how those elements connect. When those answers are incomplete, decisions are made based on assumptions – and that creates conditions where risk can grow, unnoticed.
As environments expand across cloud, SaaS, and hybrid infrastructure, the number of systems and identities grows quickly. What often falls behind is a clear understanding of how they relate to each other, and that gap is where attackers tend to operate.
How visibility gaps turn into breaches
A large medical technology organization experienced a breach driven by a series of compounding gaps rather than a single exploit. Internet-exposed assets created the initial entry point, while inconsistencies in device posture and identity enforcement, including gaps in platforms like Intune, weakened the security boundary. Attackers leveraged exposed or reused credentials and over-permissioned access to move laterally across systems. Without unified visibility across assets, identities, and managed devices, the attack path remained invisible until critical systems were reached.
Each of these conditions is common on its own, but what makes them dangerous is how they connect.
Why most attacks are not about flashy exploits
This breach did not rely on a zero-day vulnerability or an advanced technique. It depended on an exposed asset, valid credentials, and inconsistent enforcement across identity and devices. Those elements exist in most environments, but without visibility into how they overlap, they can be combined into a viable attack path.
Security teams often evaluate vulnerabilities individually, while attackers focus on how those weaknesses can be chained together. The risk is not just in what is vulnerable, but in how exposure allows movement.
What a visibility-first approach looks like
Improving outcomes depends on understanding how exposure exists across the environment and how different elements relate to each other.
Asset visibility is the starting point. Many organizations cannot confidently identify everything that is externally accessible, and attackers often find assets that were never intended to be exposed. Continuously mapping assets across cloud and on-prem environments reduces that uncertainty and limits entry points.
Identity is just as critical. Once access is established, movement depends on credentials and permissions. Stolen credentials, over-permissioned accounts, and weak authentication paths allow attackers to move beyond initial entry. Treating identity exposure as part of the attack surface helps identify these risks earlier, especially when leaked credentials can be tied to active accounts and privileges.
Attack path visibility connects these elements. Instead of evaluating findings in isolation, it shows how exposures can be combined into realistic attack scenarios. Through adversarial simulation, organizations can observe how an attacker could move from an exposed system to internal resources, which shifts focus toward removing viable paths rather than addressing isolated issues.
External signals, such as credential leaks, only become meaningful when tied back to internal systems. Monitoring for exposed credentials is useful, but correlating those credentials with active accounts and access levels is what turns that signal into something actionable.
Controls such as least privilege and multi-factor authentication remain essential, but they are only effective when applied consistently. Without visibility into where access exists, enforcement gaps are difficult to detect.
Why visibility changes the security outcome
The difference in a scenario like this is not simply better tooling. It is a shift in how exposure is understood and prioritized.
Attackers look for the easiest path through an environment. A visibility-first approach identifies those paths earlier, reduces them, and then examines why they existed. That changes how teams prioritize work, moving from reacting to individual findings toward removing viable attack paths.
How this works in practice
This is where platforms like Rapid7 support a more complete view of exposure. Surface Command aggregates telemetry from over 190 sources, helping organizations unify fragmented views of assets and identities. InsightCloudSec extends that visibility into cloud environments by enforcing best practices and least privilege without relying on manual processes. Vector Command focuses on how attackers move, using continuous testing and simulation to show how attacks would unfold across an environment.
On the intelligence side, integrating threat data with identity systems allows external signals, such as credential leaks, to be mapped to active accounts and validated in real time. That makes it possible to act before those credentials are used.
Together, these capabilities provide a clearer understanding of how exposure translates into risk.
Putting visibility at the center of security
Zero trust depends on more than policy. It requires visibility, identity, validation, and enforcement to work together continuously.
Without visibility, zero trust becomes difficult to apply in practice. With it, security decisions can be based on how systems actually behave rather than how they are expected to behave, which shifts organizations away from reacting to incidents and toward preventing them from forming.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.