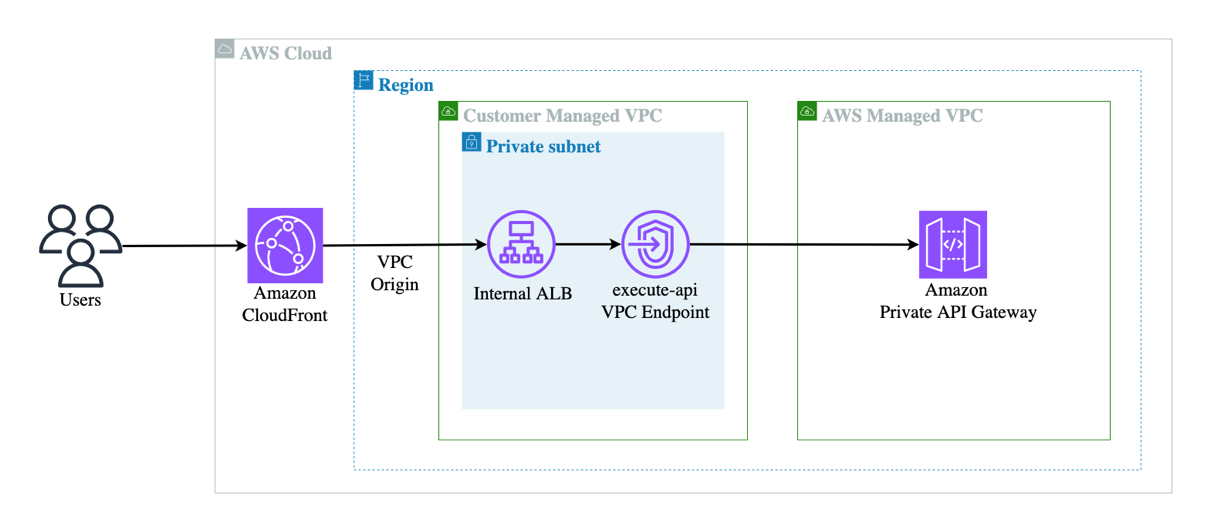
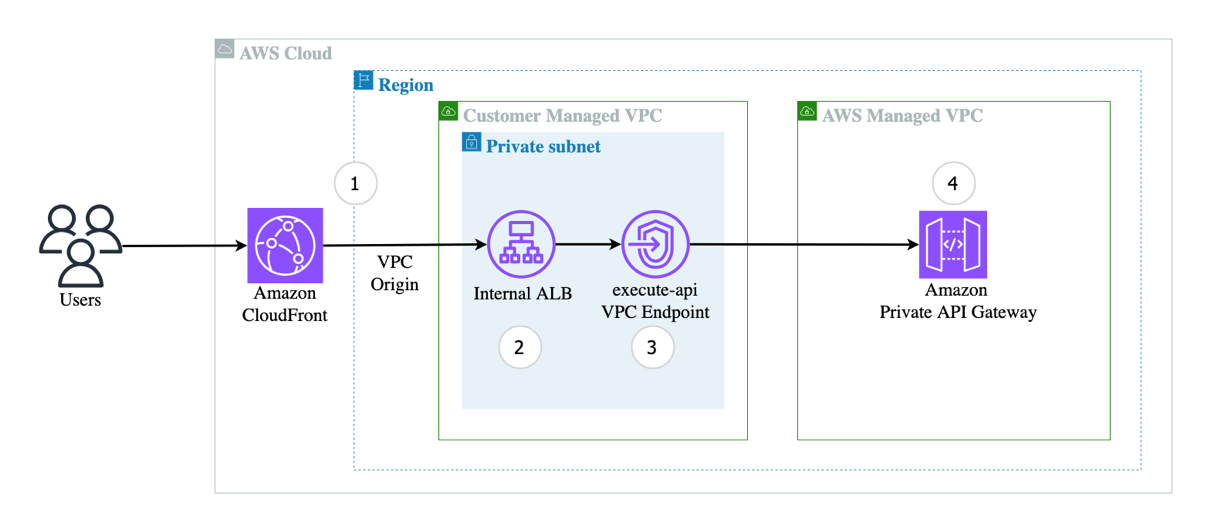
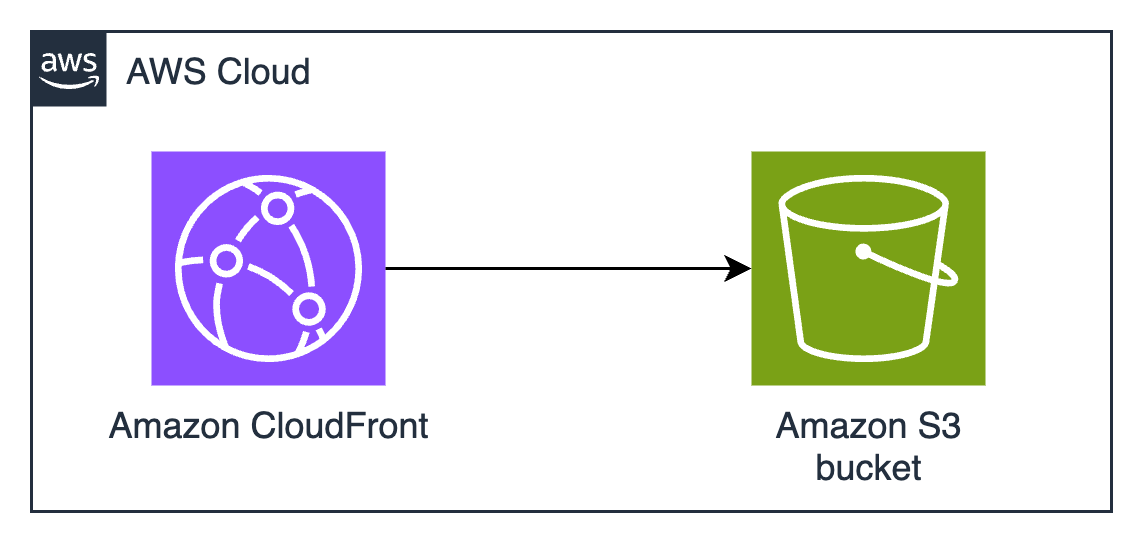
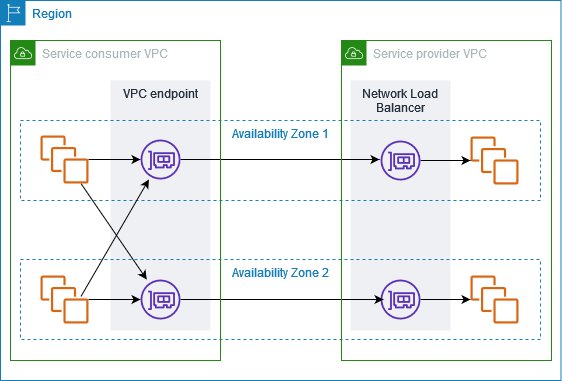
Tag Archives: Amazon CloudFront

How bitdrift scaled to 121 million concurrent gRPC connections on Amazon CloudFront for live telemetry sporting events

Post Syndicated from Raghuram Gururajan original https://aws.amazon.com/blogs/architecture/how-bitdrift-scaled-to-121-million-concurrent-grpc-connections-on-amazon-cloudfront-for-live-telemetry-sporting-events/

When 121 million mobile devices establish persistent gRPC connections to your origin infrastructure within seconds of a live broadcast, the routing policy behind your DNS records matters far more than it does at normal traffic levels. The wrong policy can concentrate all your connections onto a single origin endpoint, turning a scaling success into an outage. bitdrift, a mobile observability platform founded by former Lyft infrastructure engineers, learned this firsthand while delivering real-time telemetry for a major customer during the T20 World Cup cricket series. As matches kicked off, Amazon CloudFront absorbed traffic surging from near-zero to 110K+ peak requests per second.

bitdrift and the AWS account team diagnosed a connection concentration pattern under production pressure. The fix was a single DNS concentration change: migrating from weighted to multi-value answer routing. This change made bitdrift’s multi-Network Load Balancer (NLB’s) architecture distribute load, and they served 121 million devices with zero server-side errors.

bitdrift is a mobile observability platform (founded by ex-Lyft engineers) whose lightweight Capture performance-centric SDK provides real-time telemetry from millions of mobile devices. When bitdrift onboarded a major customer whose app serves live T20 World Cup cricket matches, they hit a scaling problem they hadn’t seen before: traffic surging from near-zero to tens of millions of concurrent gRPC connections within seconds of match start.

The DNS resolution imbalance

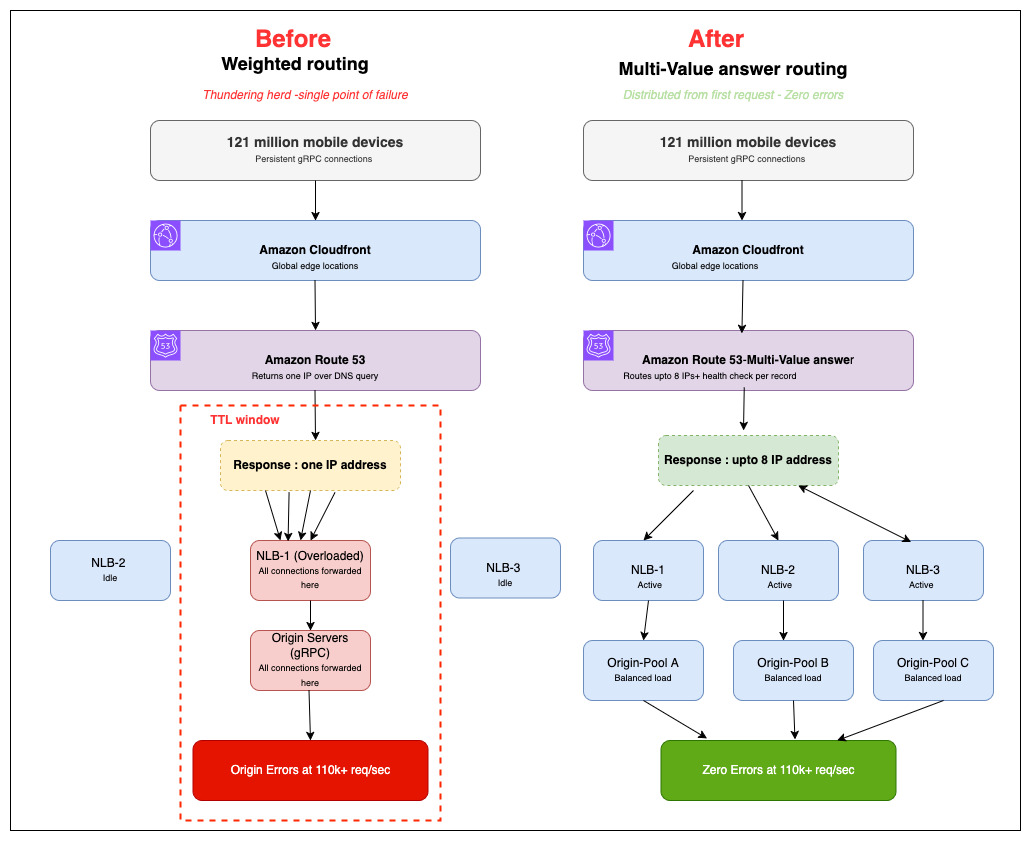
During early events in late February 2026, bitdrift experienced errors between CloudFront and their NLB origins under peak load. The AWS account team (SA, AM, TAM, CloudFront service team, and Amazon Route 53 specialists) identified the root cause: Route 53 Weighted routing was returning a single IP per DNS response. This caused all CloudFront cache hosts to resolve to the same origin for the duration of the TTL, creating a thundering herd effect that overwhelmed individual NLBs.

The TTL-driven traffic concentration

When you use weighted routing in Route 53, each DNS query returns a single IP address. At CloudFront’s scale, this means all edge nodes resolve your origin to the same load balancer for the duration of the DNS TTL. This creates a concentration effect where one NLB absorbs all traffic until the TTL expires and a new resolution occurs. Even after the customer scaled from 2 to 6 NLB IPs, the problem persisted because weighted routing returned a single IP per response. All CloudFront edge nodes resolved to the same origin for the duration of the TTL, making it appear that adding more origins had no effect.

Why persistent connections amplify this problem

Unlike short-lived HTTP requests, gRPC connections are long-lived and accumulate on whichever origin was resolved at connection time. This meant that a DNS configuration producing mild unevenness with stateless traffic caused catastrophic overload with persistent connections. Even after the customer scaled from 2 to 6 NLB IPs, the problem persisted. Weighted routing returned a single IP per response, and all CloudFront edge nodes resolved to the same origin for the duration of the TTL. This made it appear that adding more origins had no effect.

Architecture diagram

The following diagram shows the end-to-end architecture, from CloudFront edge nodes through Route 53 to the multi-region NLB fleet.
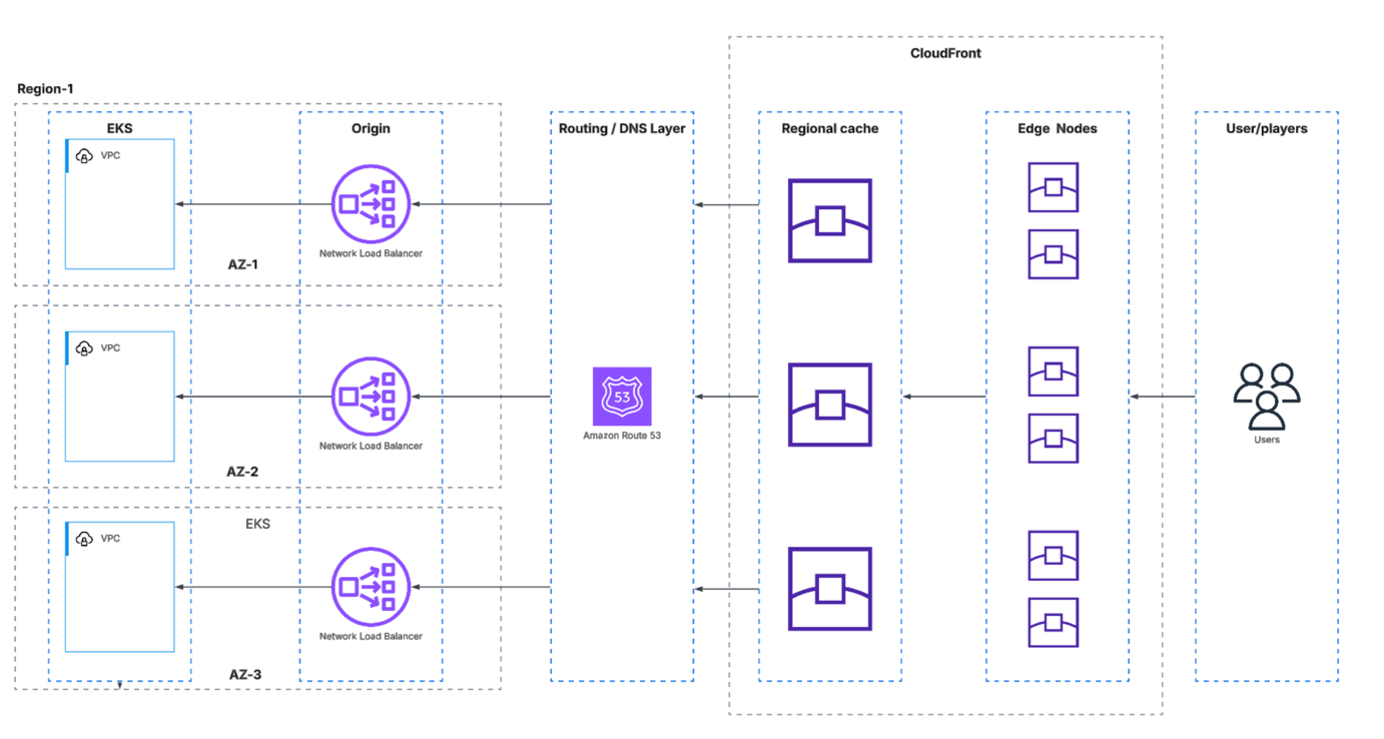
Figure 1. Amazon Route 53 is the origin-facing DNS routing layer between CloudFront and the multi-AZ Network Load Balancer (NLB) fleet. When CloudFront edge nodes need to reach the origin, they resolve the origin domain through Route 53, which directs traffic to the appropriate NLB across AZ-1, AZ-2, and AZ-3. Each NLB then forwards connections to its corresponding Amazon Elastic Kubernetes Service (Amazon EKS) workloads running within a virtual private cloud (VPC). Under Weighted routing, Route 53 returns only a single IP per DNS query, causing all edge nodes to converge on one NLB per TTL window, creating the thundering herd effect.

The fix: multi-value answer routing

Multi-Value Answer routing returns up to 8 IP addresses per DNS query, with built-in health checks per record. CloudFront edge nodes can immediately spread connections across multiple origins from the first DNS resolution, eliminating the single-origin bottleneck.

The customer-side change was straightforward:

  • bitdrift switched from Weighted to Multi-Value Answer routing, which returns up to 8 IPs per DNS response with built-in health checks spreading origin connections across multiple NLBs immediately.

The customer didn’t need to change any code or redesign their architecture. A DNS configuration update was all it took to handle 121 million concurrent devices with zero errors.
Graph showing traffic patterns during the T20 World Cup cricket series

Before vs. after comparison

Aspect Before (Weighted Routing) After (Multi-Value Routing)
IPs returned per DNS query 1 8
Origin load distribution All traffic to single NLB per TTL window Traffic spread across multiple NLBs immediately
Behavior under surge Thundering herd single NLB overwhelmed Even distribution no single point of overload
Errors at peak load Origin errors between CloudFront and NLB Zero server-side errors
Customer-side change required DNS configuration update only

Results and key metrics

Before the fix, CloudFront cache hosts resolved the origin domain to a single NLB IP per DNS TTL window (60 seconds). During traffic surges, this funneled all origin connections through a single load balancer, overwhelming its capacity.

On the February 27th event (14 million concurrent connections), approximately 80% of requests failed with HTTP 500 errors. The issue recurred on March 1st despite scaling to 4 NLB IPs. Weighted routing still returned only one IP per DNS response, so adding more origins had no effect until the routing policy was changed.

After switching to Multi-Value Answer routing on March 4th, CloudFront cache hosts immediately began resolving all 6 origin IPs simultaneously. During the next peak event, there were zero origin connection errors. By the final match on March 8th, bitdrift handled 121 million unique devices and 110K+ peak requests per second with zero server-side errors.

Key metrics

  • 121M unique devices during a single live sporting event.
  • 110K+ peak requests per second.
  • 100x traffic surge handled (near-zero to peak in seconds).
  • Zero server-side errors.
  • Minimal customer change: DNS configuration update only.

Performance before vs. after
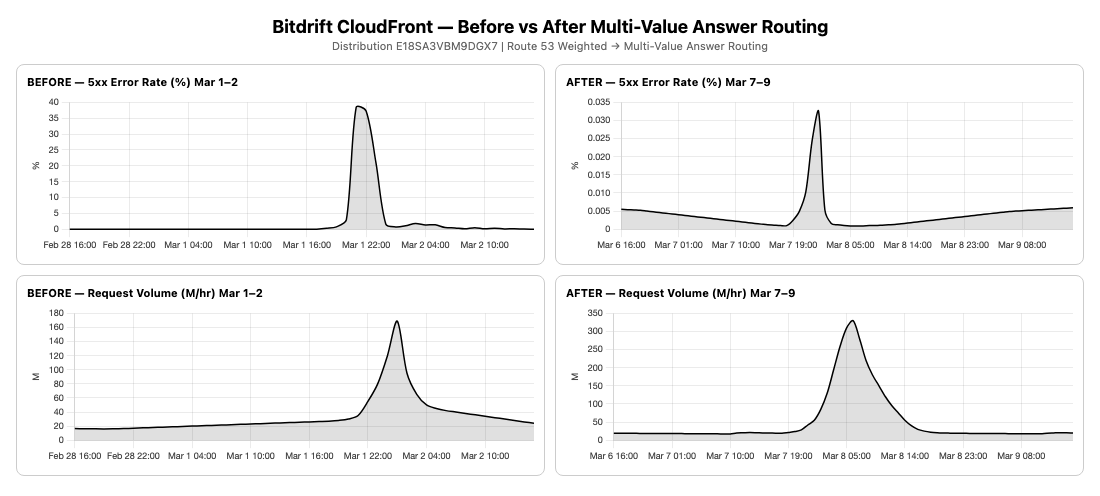
Performance comparison chart showing error rates before and after switching to multi-value answer routing

Improvement summary

Metric Before (Mar 1–2) After (Mar 7–9) Improvement
Peak 5xx Error Rate 79.80% 0.033% 99.96% reduction (2,418× better)
Avg 5xx Error Rate 1.87% 0.003% 99.84% reduction (623× better)
Peak 5-min Requests 169M 49.3M Different event scale
Peak Requests/sec 563K 164K Different event scale
Avg 4xx Error Rate 0.014% 0.007% 50% reduction
Server-Side Outages Multiple origin failures Zero 100% elimination
Unique Devices (Mar 8) 121 million 121 million Zero server-side errors

Technical walk-through

To switch your Route 53 origin records from weighted routing to multi-value answer routing, follow these steps. If you’re using CloudFront with multiple origin load balancers, this configuration ensures traffic is distributed evenly across all of them from the first request.

Prerequisites

Before you begin, make sure you have:

  • An AWS account with access to Route 53 and CloudFront.
  • A hosted zone in Route 53 for your domain.
  • Two or more NLB’s serving as CloudFront origins.
  • A CloudFront distribution configured with your origin domain.
  • AWS Command Line Interface (AWS CLI) installed (optional, for CLI steps).

Step 1: Identify your current origin records

First, check what records currently exist for your origin domain.

In the console:

  1. Open the Route 53 console.
  2. Choose Hosted zones in the left navigation.
  3. Select your hosted zone (for example, origin.example.com).
  4. Find the records for your origin domain (for example, origin.example.com).
  5. Note the routing policy. If it says Weighted, this guide applies to you.

Using the CLI:

aws route53 list-resource-record-sets \
  --hosted-zone-id Z1234567890ABC \
  --query "ResourceRecordSets[?Name=='origin.example.com.']"

You’ll see something like:

[
  {
    "Name": "origin.example.com.",
    "Type": "A",
    "SetIdentifier": "nlb-1",
    "Weight": 50,
    "AliasTarget": {
      "DNSName": "nlb-1-abcdef.elb.us-east-1.amazonaws.com.",
      "HostedZoneId": "Z26RNL4JYFTOTI",
      "EvaluateTargetHealth": true
    }
  },
  {
    "Name": "origin.example.com.",
    "Type": "A",
    "SetIdentifier": "nlb-2",
    "Weight": 50,
    "AliasTarget": {
      "DNSName": "nlb-2-ghijkl.elb.us-east-1.amazonaws.com.",
      "HostedZoneId": "Z26RNL4JYFTOTI",
      "EvaluateTargetHealth": true
    }
  }
]

Step 2: Create health checks for each origin

Multi-Value Answer routing requires a health check attached to each record. The main advantage here is that unhealthy origins are automatically removed from the DNS responses.

In the console:

  1. In Route 53, choose Health checks in the left navigation.
  2. Choose Create health check.
  3. Configure:
  • Name: nlb-1-health-check.
  • What to monitor: Endpoint.
  • Specify endpoint by: Domain name.
  • Protocol: TCP (or HTTP/HTTPS if your origin supports it).
  • Domain name: nlb-1-abcdef.elb.us-east-1.amazonaws.com.
  • Port: Your origin port (for example, 443).
  • Request interval: 10 seconds (Fast) recommended for burst traffic patterns.
  • Failure threshold: 3.
  1. Choose Create health check.
  2. Repeat for each NLB.

Using the CLI:

aws route53 create-health-check \
  --caller-reference "nlb-1-health-$(date +%s)" \
  --health-check-config '{
    "Type": "TCP",
    "FullyQualifiedDomainName": "nlb-1-abcdef.elb.us-east-1.amazonaws.com",
    "Port": 443,
    "RequestInterval": 10,
    "FailureThreshold": 3
  }'

Step 3: Create multi-value answer records

Note: Multi-Value Answer routing requires IP address records, not Alias records. Assign Elastic IP addresses to each NLB Availability Zone before proceeding — Application Load Balancers are not compatible with this pattern because they do not support static IP addresses.

Now create the new records with Multi-Value Answer routing.

In the console:

  1. Choose Create record.
  2. Configure:
  • Record name: origin (or your subdomain)
  • Record type: A.
  • Routing policy: Multi-Value Answer.
  • Value/Route traffic to: Enter the IP address of your first NLB (or use the NLB’s static IP).
  • Health check: Select the health check you created for this NLB.
  • Record ID: nlb-1 (a unique ID for this record)
  • TTL: 60 seconds (keep it low for faster failover).
  1. Choose Create records.
  2. Repeat for each NLB.

Using the CLI:

aws route53 change-resource-record-sets \
  --hosted-zone-id Z1234567890ABC \
  --change-batch '{
    "Changes": [
      {
        "Action": "CREATE",
        "ResourceRecordSet": {
          "Name": "origin.example.com.",
          "Type": "A",
          "SetIdentifier": "nlb-1",
          "MultiValueAnswer": true,
          "TTL": 60,
          "ResourceRecords": [{"Value": "10.0.1.100"}],
          "HealthCheckId": "abcd1234-5678-90ab-cdef-EXAMPLE1"
        }
      },
      {
        "Action": "CREATE",
        "ResourceRecordSet": {
          "Name": "origin.example.com.",
          "Type": "A",
          "SetIdentifier": "nlb-2",
          "MultiValueAnswer": true,
          "TTL": 60,
          "ResourceRecords": [{"Value": "10.0.2.100"}],
          "HealthCheckId": "abcd1234-5678-90ab-cdef-EXAMPLE2"
        }
      }
    ]
  }'

Step 4: Delete the old weighted records

Once you’ve verified the Multi-Value Answer records are returning correctly (Step 5), delete the original Weighted routing records. Route 53 does not allow mixed routing policies for the same record name. The old Weighted records must be removed.

Step 5: Verify the configuration

dig origin.example.com +short

You should see multiple IPs returned simultaneously:

10.0.1.100
10.0.2.100
10.0.3.100

Summary of challenges

Resolving the issue under production pressure presented several challenges:

  • Diagnosing under fire: The initial outage occurred during a live T20 World Cup match with 14 million concurrent connections. Root cause analysis had to happen in real-time while the customer’s production traffic was failing.
  • Persistent connections amplify DNS routing issues: Unlike short-lived HTTP requests, gRPC connections are long-lived and accumulate on whichever origin was resolved at connection time. This meant that a DNS configuration producing mild unevenness with stateless traffic caused catastrophic overload with persistent connections.
  • DNS caching obscured the real bottleneck: Even after the customer scaled from 2 to 6 NLB IPs, the problem persisted. Because Weighted routing returned a single IP per response, all CloudFront edge nodes resolved to the same origin for the duration of the TTL. This made it appear that adding more origins had no effect.
  • Customer coordination under time pressure: The customer was initially reluctant to change their Route 53 configuration ahead of the next match. Working with the AWS account team to build confidence in the DNS change while a live event was days away required clear communication of the root cause and expected impact.

Conclusion

This case demonstrates that at extreme scale, infrastructure decisions that seem routine can become the difference between a flawless event and a production outage. Choosing a DNS routing policy is one such decision. bitdrift’s architecture was sound: CloudFront at the edge, NLBs at the origin, gRPC for efficient persistent connections. But Weighted routing’s single-IP-per-response behavior created a thundering herd that no amount of origin scaling could overcome.

The fix was purely configuration: switching from weighted to multi-value answer routing in Route 53. After that change, bitdrift handled 121 million concurrent devices with zero errors.

If you’re running CloudFront with multiple origin load balancers, especially with persistent connection protocols like gRPC or WebSocket, review your Route 53 routing policy. Multi-Value Answer routing ensures that CloudFront edge nodes distribute origin connections across all available endpoints from the first DNS resolution. This eliminates the single-origin bottleneck that Weighted routing can create under surge conditions.

For pre-event capacity planning or to discuss your architecture with an AWS specialist, contact your AWS account team or reach out through AWS Support.

Key takeaways

  1. DNS routing policy selection matters at extreme scale. Weighted vs. Multi-Value Answer has significant implications for origin load distribution behind CloudFront.
  2. Persistent connections (gRPC, WebSocket) amplify DNS routing problems. Unlike stateless HTTP where connections are short-lived, persistent connections accumulate on whichever origin was resolved at connection time. A DNS misconfiguration that causes mild unevenness with HTTP traffic can cause catastrophic overload with persistent connections.
  3. Engaging AWS service teams early for pre-event capacity reviews prevents day-of failures.
  4. A DNS configuration change can improve scale without requiring any architectural changes.
About the authors

Dual-token authentication for Nakama game servers with Amazon Cognito on AWS

Post Syndicated from Madhusudan Athinarapu original https://aws.amazon.com/blogs/architecture/dual-token-authentication-for-nakama-game-servers-with-amazon-cognito-on-aws/

When your game server needs both a managed identity provider and its own session system, players face a broken experience if authentication forces a redirect or stalls gameplay. Dual-token authentication for Nakama game servers with Amazon Cognito solves this by connecting two independent session systems, each with its own token lifecycle, without interrupting the player. This post shows you how.

Amazon Cognito handles player identity and Nakama manages game sessions. Cognito issues a JWT, a server-side Go hook validates it and exchanges the verified identity for a Nakama session token. Each token is validated independently on every request. The pattern applies to game servers such as Nakama that support runtime authentication hooks.

The infrastructure wraps Nakama in a default-closed routing layer. Amazon CloudFront serves as the single HTTPS entry point, AWS WAF filters traffic at the edge, an Application Load Balancer (ALB) enforces an explicit route allow-list for HTTP, and a Network Load Balancer (NLB) handles WebSocket TCP passthrough. Nakama runs on Amazon Elastic Container Service (Amazon ECS) on AWS Fargate. In this post, we cover the Cognito configuration, the Go hook, the Terraform infrastructure, and the WebSocket lifecycle controls.

In this post, you learn how to:

  1. Configure an Amazon Cognito User Pool for SRP-based game client authentication with no client secret.
  2. Implement a Go runtime hook that validates Cognito JWTs and bridges player identity to Nakama sessions.
  3. Set up a default-closed routing layer using Amazon CloudFront, an ALB, and an NLB.
  4. Manage the WebSocket connection lifecycle under the NLB TCP idle timeout model.

Solution overview

The architecture has four layers for authenticating and routing traffic.

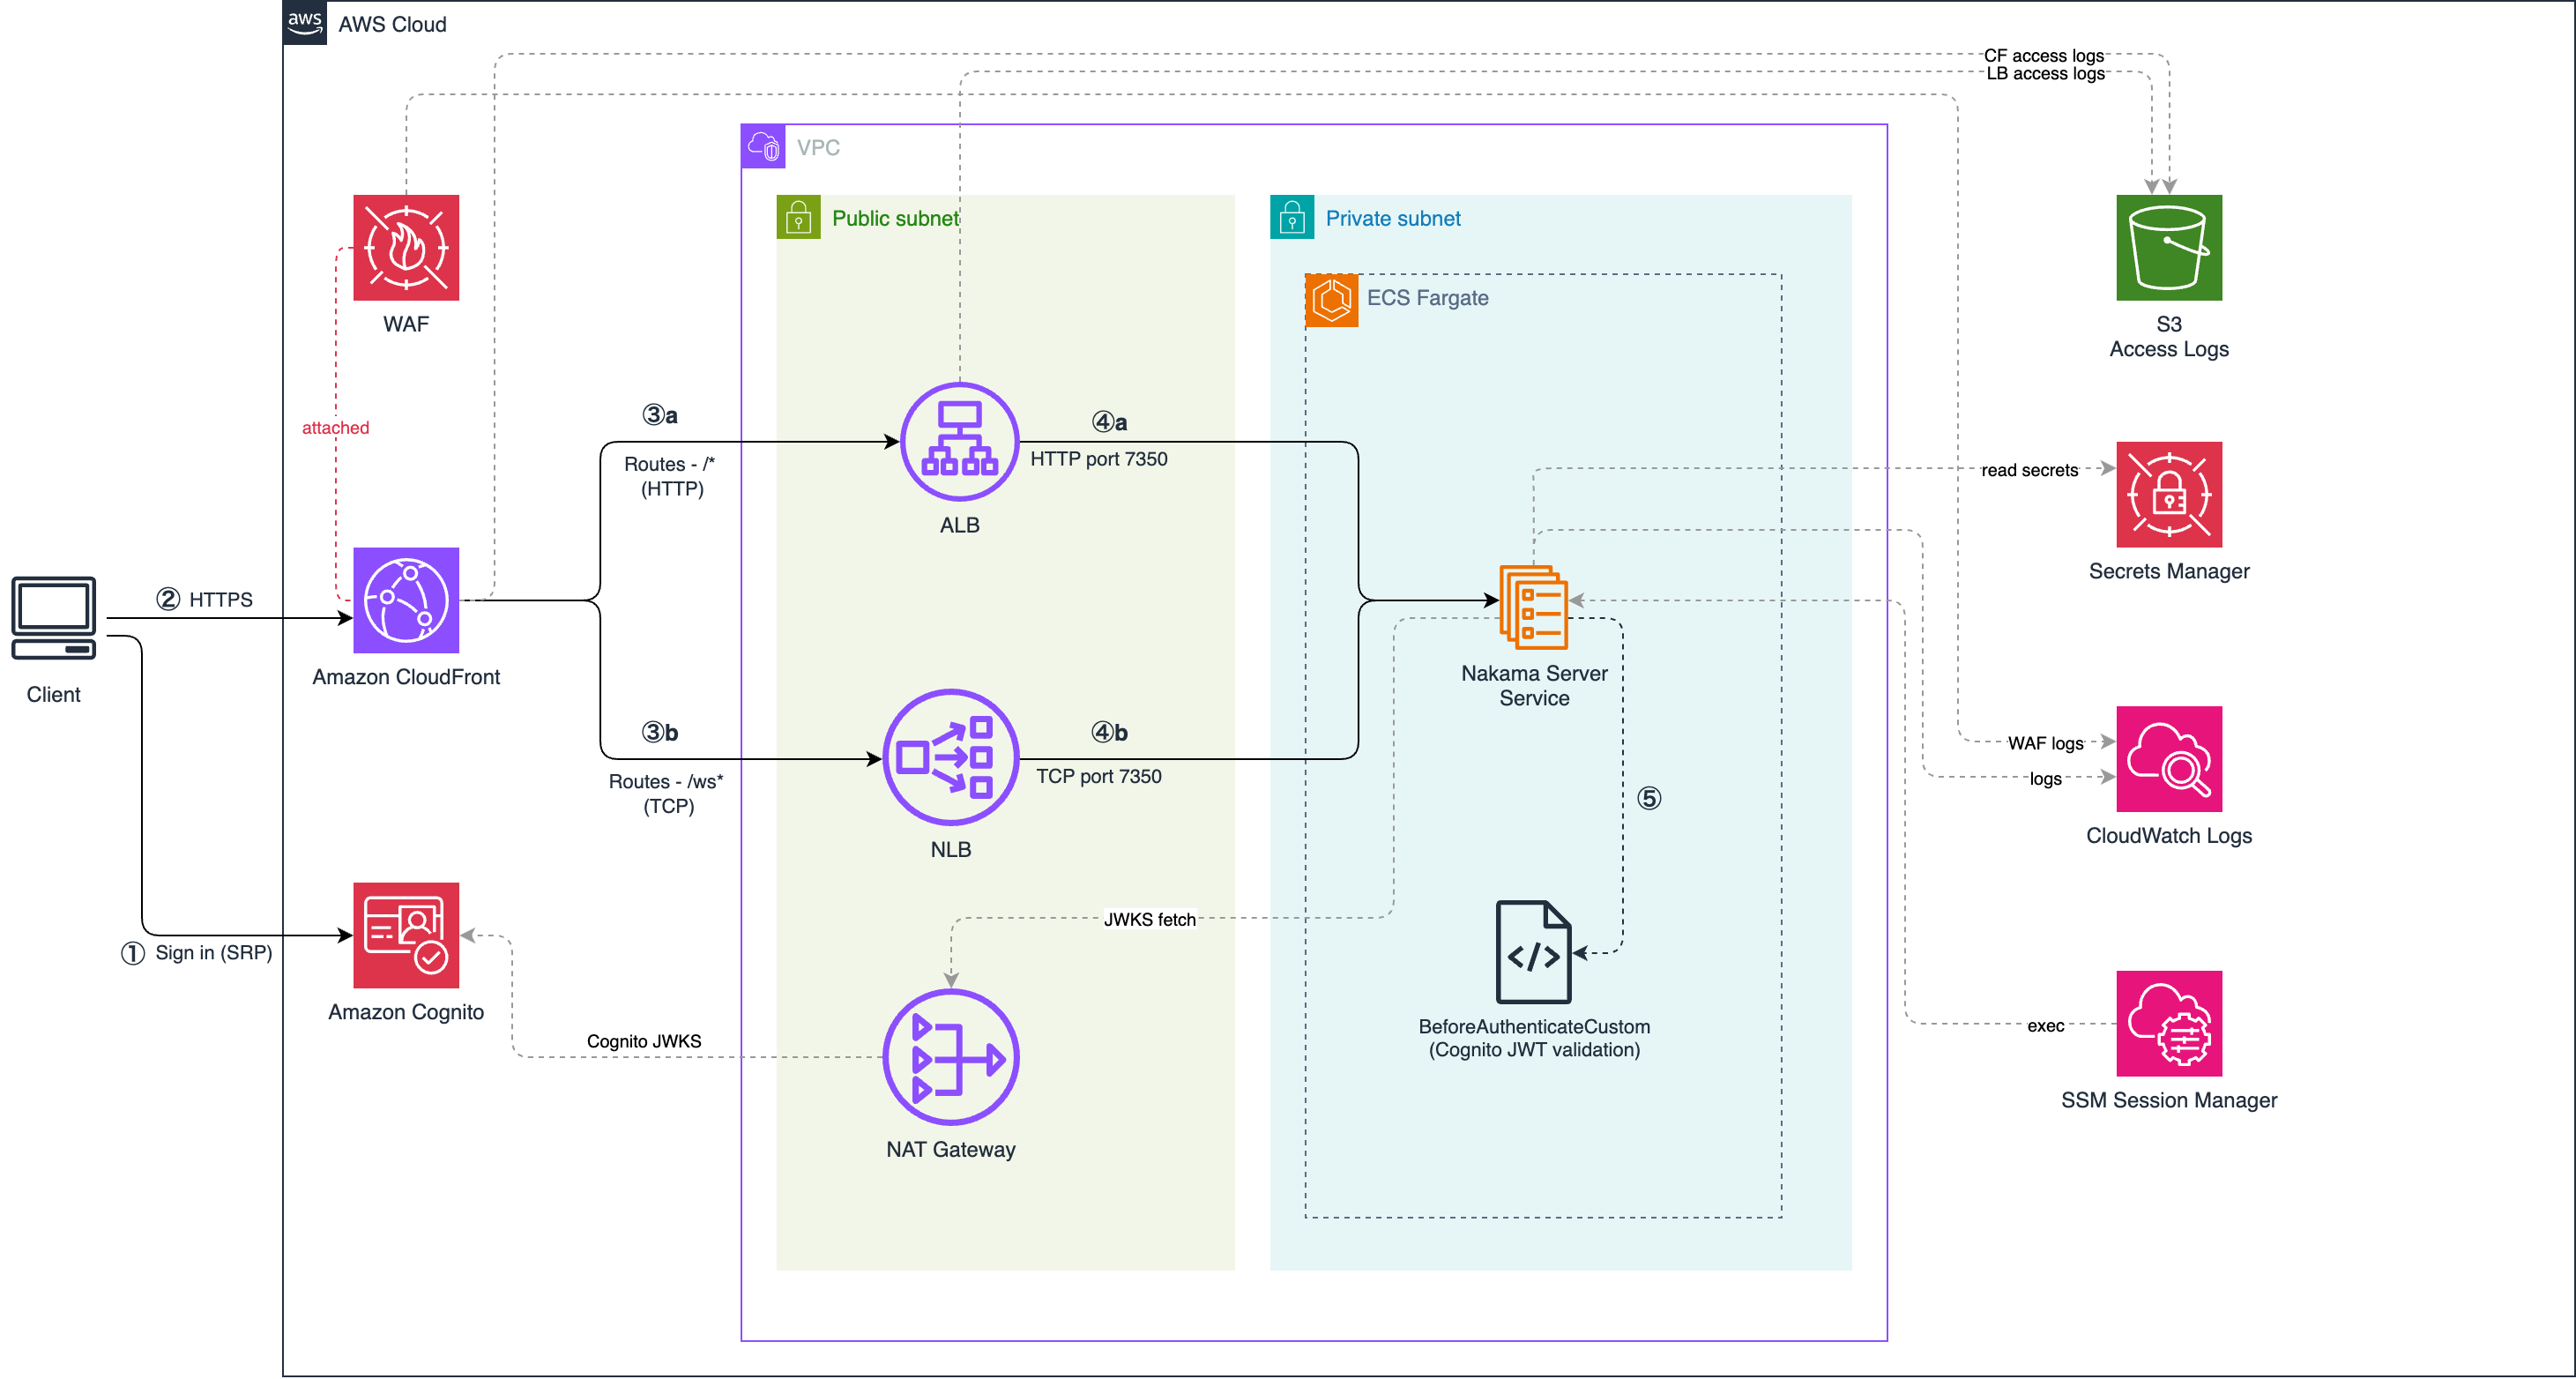
The following diagram shows the architecture. Amazon CloudFront is the single entry point, routing HTTP API traffic through an Application Load Balancer (ALB) to Nakama on Amazon ECS, and WebSocket traffic through a Network Load Balancer (NLB) via TCP passthrough.

Architecture diagram showing dual-token authentication flow from client through Amazon CloudFront, ALB, and NLB to Nakama on Amazon ECS

Figure 1. Dual-token authentication architecture for Nakama on AWS.

Traffic flows through the system in six steps:

  1. Client → Amazon Cognito — The player authenticates using USER_SRP_AUTH. The password never leaves the client. Amazon Cognito returns a JWT access token.
  2. Client → Amazon CloudFront — Requests enter via Amazon CloudFront (HTTPS). AWS WAF inspects traffic at the edge before it reaches the origin.
  3. CloudFront → ALB (port 80) — /* HTTP API traffic. The ALB is security-group locked to the CloudFront managed prefix list only.
  4. CloudFront → NLB (port 7350) — /ws* WebSocket traffic. The NLB performs TCP passthrough with no HTTP inspection.
  5. ALB → Amazon ECS (Nakama) — For auth requests: the BeforeAuthenticateCustom Go hook validates the Cognito JWT and extracts the sub claim as the Nakama user ID. For other API calls: Nakama validates its own session token.
  6. NLB → Amazon ECS (Nakama) — Persistent WebSocket connection. Nakama validates the session token from the token query parameter at connect time.

Why two load balancers

The ALB and NLB serve different purposes and cannot be combined into one.

The ALB operates at the HTTP layer (Layer 7). It reads the path, applies listener rules, and returns 403 for unlisted routes.

The NLB operates at the TCP layer (Layer 4) and passes the raw stream to Nakama unchanged. Nakama receives the WebSocket upgrade directly from the client, validates the session token, and manages the connection lifecycle end-to-end.

Amazon CloudFront routes /ws* to the NLB and everything else to the ALB, so each connection type gets the appropriate handling behind a single HTTPS endpoint.

Prerequisites

Before you deploy this solution, make sure you have:

  1. Terraform >= 1.5.0 (download).
  2. Go >= 1.21 (to build the Nakama plugin locally).
  3. Docker and the AWS Command Line Interface (AWS CLI) configured with appropriate credentials.

The repository includes a browser-based test app (/app) that demonstrates the full sign-up, sign-in, and Nakama token exchange flow.

Authenticate players with Amazon Cognito

Amazon Cognito provides a managed user directory that issues JWTs without requiring you to run your own identity server or store credentials. The game server validates the JWT independently on each request, with no callback to Cognito needed. This decouples identity from game sessions: Cognito owns the player’s identity, Nakama owns the game session, and neither system depends on the other at runtime.

Players self-register by calling the Cognito SignUp API from the game client. The User Pool verifies their email before the account becomes active. After sign-in, Cognito returns a JWT access token containing the player’s sub claim (a UUID), which becomes the Nakama user ID in the next step.

Authentication uses the USER_SRP_AUTH flow. The password never leaves the client device. The User Pool App Client is configured as a public client with no client secret, since your game client runs in the browser or a native app where any embedded secret is extractable. With SRP, no secret is needed; security comes from the protocol itself.

After a successful sign-in, Amazon Cognito returns a JWT access token. This token carries the player’s identity claims and is signed with an RSA key pair unique to your User Pool. The sub claim — a UUID generated by Cognito — uniquely identifies the player and becomes the Nakama user ID in the next step.

The auth Terraform module configures the App Client with generate_secret=false and permits only ALLOW_USER_SRP_AUTH and ALLOW_REFRESH_TOKEN_AUTH flows. The resulting JWT access token is short-lived (1 hour by default) and carries the sub, iss, exp, and client_id claims that the Go hook validates in the next step.

Bridge Cognito identity to Nakama sessions

Nakama’s server-side runtime supports Go plugins exclusively. The hook in this section is written in Go using Nakama’s runtime.Initializer interface. This is a constraint of the Nakama runtime model.

Once the client has a Cognito JWT, it needs a Nakama session token to make game API calls.

Validate the Cognito JWT in the Go hook

The game server cannot trust the identity claim sent by the client directly. Any client can forge a user ID. JWT validation cryptographically proves the identity was issued by Cognito, preventing player impersonation.

The hook performs five checks in order: token format, algorithm (RS256 only), signature against the JWKS, expiry, and issuer/audience matching your specific User Pool.

func validateCognitoJWT(token string, env map[string]string) (string, error) {
    parts := strings.Split(token, ".")
    if len(parts) != 3 {
        return "", runtime.NewError("invalid token format", 3)
    }

    // Parse the header to get the key ID (kid)
    var header struct {
        Kid string `json:"kid"`
        Alg string `json:"alg"`
    }
    headerBytes, _ := base64.RawURLEncoding.DecodeString(parts[0])
    json.Unmarshal(headerBytes, &header)

    if header.Alg != "RS256" {
        return "", runtime.NewError("unsupported algorithm: "+header.Alg, 3)
    }

    // Fetch the public key from the JWKS cache
    pubKey, err := jwksCache.getKey(header.Kid)
    if err != nil {
        return "", runtime.NewError("token validation failed", 16)
    }

    // Verify the RSA signature
    hash := sha256.Sum256([]byte(parts[0] + "." + parts[1]))
    signatureBytes, _ := base64.RawURLEncoding.DecodeString(parts[2])
    if err := rsa.VerifyPKCS1v15(pubKey, crypto.SHA256, hash[:], signatureBytes); err != nil {
        return "", runtime.NewError("invalid token signature", 16)
    }

    // Validate claims: expiry, issuer, audience
    if time.Now().Unix() > claims.Exp { return "", runtime.NewError("token expired", 16) }
    if claims.Iss != expectedIssuer || claims.ClientID != env["COGNITO_CLIENT_ID"] {
        return "", runtime.NewError("invalid issuer or audience", 16)
    }

    return claims.Sub, nil // sub claim becomes the Nakama user ID
}

Security note: The hook never trusts the identity string sent by the client. It discards it and overwrites the Nakama user ID with the sub claim from the validated JWT. A client that sends a forged sub cannot impersonate another player — the hook ignores the body value entirely.

Cache JWKS keys with thundering herd protection

Amazon Cognito rotates its signing keys periodically. The hook caches keys with a 1-hour TTL. A 30-second re-fetch guard prevents multiple goroutines from calling the JWKS endpoint simultaneously when the cache expires.

func (c *JWKSCache) refresh() error {
    c.mu.Lock()
    defer c.mu.Unlock()

    // Thundering herd protection: if another goroutine already
    // refreshed within the last 30s, use the updated cache
    if time.Since(c.fetched) < 30*time.Second {
        return nil
    }

    // ... fetch and parse JWKS from Cognito endpoint
}

Register the hook

The hook registers itself in InitModule, the entry point called by Nakama when the plugin loads:

func InitModule(ctx context.Context, logger runtime.Logger, db *sql.DB,
    nk runtime.NakamaModule, initializer runtime.Initializer) error {

    if err := initializer.RegisterBeforeAuthenticateCustom(beforeAuthenticateCustom); err != nil {
        return fmt.Errorf("failed to register hook: %w", err)
    }
    logger.Info("Cognito JWT validation hook registered")
    return nil
}

When the client calls POST /v2/account/authenticate/custom with the Cognito JWT as the id field, Nakama calls beforeAuthenticateCustom before processing the request. If the JWT is valid, the hook sets in.Account.Id = sub and returns. Nakama creates or links the account and returns a session token to the client.

If your server is not Nakama, for example, Colyseus, Photon, or a custom WebSocket server, implement the same five checks (algorithm, signature, expiry, issuer, audience) in your server’s middleware or plugin language. The JWKS endpoint and JWT structure follow the OIDC standard, so any OIDC-compliant identity provider (not only Amazon Cognito) works with this pattern.

Deploy the infrastructure

The infrastructure is organized into six Terraform modules: network (Amazon Virtual Private Cloud (Amazon VPC), subnets, security groups), compute (Amazon ECS cluster, ALB, NLB, Amazon Elastic Container Registry (Amazon ECR)), auth (Cognito User Pool), cdn (CloudFront distribution), waf-cloudfront (AWS WAF Web ACL), and ops (IAM, AWS Systems Manager access). A bootstrap module creates the S3 state backend and AWS Key Management Service (AWS KMS) key before the main deployment.

Deploy with:

# One-time: provision the Terraform state backend
cd terraform/bootstrap && terraform init && terraform apply

# Deploy everything
cd terraform && terraform init -backend-config=config/backend-dev.hcl
make deploy

make deploy builds and pushes the Nakama container image to Amazon ECR, then runs terraform apply. The image tag auto-increments from the latest tag in ECR.

ALB routing: explicit allow list

The ALB default listener action returns 403. Only the paths in the following table reach Nakama. Requests to unlisted paths are rejected before they reach the game server.

Priority Path Target Purpose
1 /healthcheck Nakama port 7350 Health monitoring
2 /v2/account/authenticate/* Nakama port 7350 Session bridge: Go hook validates JWT
10 /v2/* Nakama port 7350 Nakama REST API v2
11 /v1/* Nakama port 7350 Nakama RPC (v1)
Default * 403 Forbidden Request never reaches Nakama

The default-403 posture means a misconfigured client or a scanner probing arbitrary paths gets a 403 at the ALB, not an error from the game server. This limits the attack surface to the explicitly listed API surface.

Security group chain

The network layer enforces two security group rules:

  1. The ALB security group allows inbound only from the CloudFront managed prefix list. As an additional application-layer check, CloudFront sends a shared secret in the X-CloudFront-Secret header on every request; ALB listener rules reject any request missing the correct value with a 403. The NLB security group applies the same CloudFront managed prefix list restriction at Layer 4.
  2. The NLB security group allows inbound TCP 7350 only from the CloudFront managed prefix list. The ECS task security group allows inbound port 7350 only from the ALB security group (HTTP API) and from the NLB security group (WebSocket).

Together, the routing and security group chain means the only path to Nakama is: Internet → CloudFront → AWS WAF → ALB or NLB → ECS. No hop can be skipped.

Manage the WebSocket connection lifecycle

The NLB TCP passthrough model creates a lifecycle challenge: the NLB drops idle TCP flows after 350 seconds (the AWS default, not configurable). If a player’s connection sits idle, the NLB closes the underlying TCP connection while Nakama still holds an open socket.

The following table describes the four controls that handle this:

Control Value Purpose
NLB TCP idle timeout 350s NLB drops idle TCP flows. Cannot be changed.
Nakama ping interval 10s Nakama sends a WebSocket ping every 10s, keeping the TCP flow active.
Nakama pong wait 20s If the client does not respond to a ping within 20s, Nakama closes the connection.
token_expiry_sec 7200 Nakama rejects session tokens older than 2 hours at connect time.
single_socket true A new connection from the same user kills the previous one, preventing stale sessions.

The ping/pong keepalive

The 10-second ping interval is the key control. Nakama sends a WebSocket ping frame every 10 seconds on each active connection. The client responds with a pong. This keeps the NLB TCP flow alive well within the 350-second idle timeout. If the client goes silent, Nakama detects the missing pong within 20 seconds and closes the socket cleanly.

Session expiry at connect time

The NLB performs TCP passthrough, so there is no opportunity to inspect HTTP headers or validate the session token at the network layer. Nakama validates the session token from the token query parameter when the WebSocket upgrade request arrives. A token older than token_expiry_sec is rejected and the connection is closed before any game messages are processed.

Single socket enforcement

single_socket: true verifies that when a player opens a second connection (after a network drop and reconnect, for example) the server closes the first connection. Without this, a player’s Nakama state can be split across two concurrent connections if the client does not cleanly close the first one.

The four-layer model (keepalive, timeout, session expiry at connect, one-connection-per-user enforcement) applies to any real-time server behind an NLB TCP passthrough: Colyseus, Photon, custom WebSocket backends, or any game server that manages persistent connections. If your server does not have built-in ping/pong, implement application-level heartbeat messages that serve the same role.

Security note: The session token travels as a query parameter (?token=...) in the WebSocket upgrade URL. Query parameters appear in server access logs, load balancer logs, Amazon CloudFront logs, and browser history. Mitigations: all connections use TLS (token encrypted in transit), session tokens are short-lived (2 hours), and single_socket invalidates old connections on reconnect. For production deployments, consider log redaction policies for the token parameter.

Clean up

To avoid ongoing AWS charges, destroy all resources when you no longer need them.

Destroy the main infrastructure first:

cd terraform && terraform destroy

Then destroy the Terraform state backend:

cd terraform/bootstrap && terraform destroy

Confirm resources are removed by running terraform state list (should return empty) or checking the AWS Management Console.

Conclusion

In this post, you implemented a dual-token authentication architecture for a Nakama game server on AWS. Amazon Cognito handles player identity through JWT validation; a Go runtime hook bridges verified identity into Nakama sessions; and the infrastructure enforces a routing layer where HTTP API traffic passes through an Application Load Balancer with an explicit allow list and WebSocket connections reach Nakama directly through a Network Load Balancer TCP passthrough.

The four-layer WebSocket lifecycle model can be applied to real-time game servers behind an NLB TCP passthrough, not Nakama exclusively.

For production deployments, consider these next steps:

  1. Replace the PostgreSQL sidecar with Amazon Aurora PostgreSQL-Compatible Edition for persistent, managed player data storage.
  2. Add a custom domain with TLS re-encryption between Amazon CloudFront and the ALB.
  3. Add Amazon VPC endpoints for Amazon Cognito and AWS Secrets Manager to eliminate the NAT Gateway dependency.

The full Terraform modules and Go plugin are available in the GitHub repository.

For more on Cognito-based game authentication patterns, refer to Using Amazon Cognito to Authenticate Players for a Game Backend Service and Web application access control patterns using AWS services.

Share your questions and feedback in the comments.


About the authors

How Samsung achieved real-time pricing with AWS Lambda Response Streaming

Post Syndicated from Vijay Naik original https://aws.amazon.com/blogs/architecture/how-samsung-achieved-real-time-pricing-with-aws-lambda-response-streaming/

This post is co-authored with Sathish Kumar and Christopher Chan from Samsung ecommerce.

In high-traffic ecommerce, achieving real-time pricing is critical to prevent price inconsistency. Pricing inconsistency creates cart shock and erodes trust. This isn’t broken software, it’s a symptom of architectural latency that you can address using AWS Lambda Response Streaming and Amazon CloudFront for systems aggregating data from multiple backend sources.

In this post, we walk through the legacy architecture challenges, the stateless streaming solution, key implementation patterns, and performance results—a pattern you can apply if you’re building high-traffic APIs that aggregate data from multiple backend sources.

Samsung.com is Samsung’s primary direct-to-consumer channel, selling smartphones, TVs, appliances, and accessories, each with multiple variants, offers, and regional pricing. This complexity makes real-time price accuracy especially important.

Samsung’s All Deals and Product Finder pages showcase these products during high-traffic events like Black Friday. To maintain low latency for these high-density Product Listing Pages (PLPs) and comparison tables, the legacy infrastructure relied on asynchronous caching, which introduced a desynchronization gap where the cached price drifted from the authoritative pricing engine.

Problem: Legacy middleware caching created a 1-hour desynchronization gap between the authoritative pricing engine and customer-facing pages.

Our approach: We dismantled the stateful Data Aggregation (DA) architecture and built a real-time Bulk Arbitration Engine (a stateless orchestration layer that queries the Pricing Engine directly at request time) using AWS Lambda Response Streaming and Amazon CloudFront edge caching.

Challenge: The Data Aggregation trap

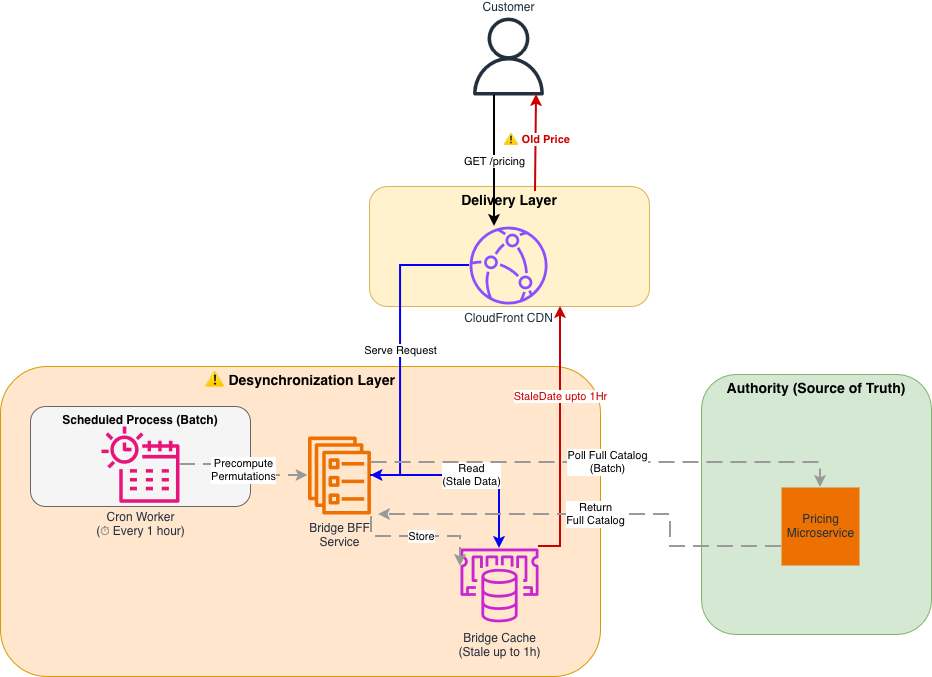
When product listing pages need to display pricing for over 30 item combinations simultaneously, the latency of calling the Pricing Engine for each item combination individually becomes untenable. To solve this, we built a backend for frontend (BFF) service to do a “Data Aggregation. This DA service was designed to decouple the frontend from the heavy Pricing Engine.

It relied on a scheduled Cron Worker that ran hourly to fetch the entire product catalog. The worker would then precompute prices for every possible permutation of products and store them in a local cache.

While this improved read speeds, it created two significant failures:

1. The Permutation Explosion – The DA service had to precompute every combination just in case a customer viewed it.

  • The Math: 30 products × (Variants × Offers × Add-ons) = Thousands of records per page
  • Storage Impact: Cache grew exponentially with each new product variant added
  • Waste: Most precomputed combinations were never requested

2. The Synchronization Lag – Because the Cron job ran only once per hour, price changes (for example, flash sales) lagged significantly. Customers continued to see old prices until the next scheduled sync.

  • Business Impact: Flash sales showed incorrect old pricing until the next run time
  • Customer Trust: Cart shock when checkout price differed from product page price
  • Competitive Disadvantage: Competitors with real-time pricing gained market share

Legacy Data Aggregation architecture

Architecture diagram showing the legacy Data Aggregation layer between the Pricing Engine and CloudFront CDN.

Architecture diagram showing the legacy Data Aggregation layer between the Pricing Engine and CloudFront CDN

Figure 1: Legacy Data Aggregation (DA) Architecture The legacy system relied on a scheduled Cron job, creating a distinct “Desynchronization Layer” between the Authority (Pricing) and the Customer. Precomputation of all product permutations consumed significant storage and compute resources.

The solution: Stateless streaming architecture

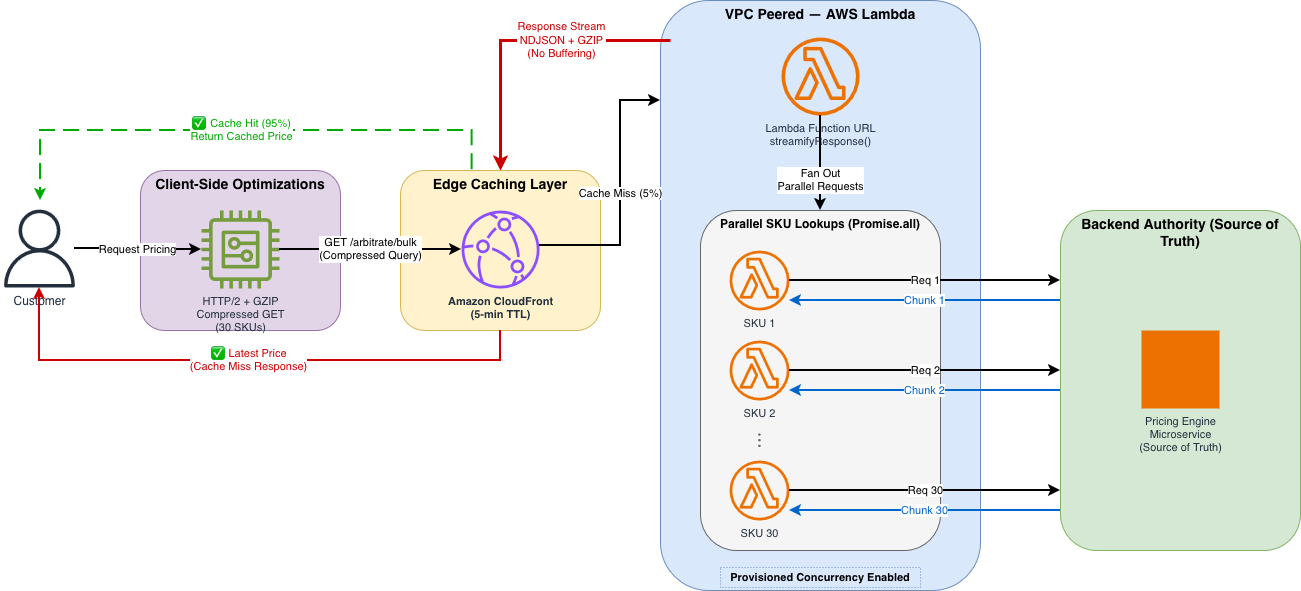
Intermediate layers storing data will eventually diverge from the source, so we collaborated with our AWS Technical Account Manager (TAM) and service teams to architect a new solution: the Bulk Arbitration Engine, a stateless orchestration layer that queries the Pricing Engine directly at request time.

The new architecture follows a Pass-Through pattern:

1. Client Request: The browser requests prices for 30 specific SKUs using a single HTTP GET request.

2. Streaming Orchestration: An AWS Lambda function fans out these 30 requests to the Pricing Engine in parallel.

3. Immediate Response: As the Pricing Engine returns data, the Lambda streams it immediately to the client without buffering.

Why Lambda Response Streaming?

We evaluated several alternatives before settling on this approach:

  • Traditional request-response pattern (buffered) – A standard Lambda invocation buffers the full response before returning it to the client, which negates the latency benefit of parallel fan-out. For 30 concurrent SKU lookups, this added seconds of wait time.
  • EC2 with improved caching – This was the legacy approach. Caching layers will eventually drift from the source of truth, which was the core problem we needed to solve.
  • Lambda Response Streaming – This was the only option that let us fan out requests in parallel, stream results as they arrived (reducing time-to-first-byte), and remain fully stateless with no intermediate cache to maintain or invalidate.

New stateless streaming architecture

New stateless Lambda Response Streaming architecture with CloudFront caching layer directly connected to Lambda function, which streams real-time responses from Pricing Engine without intermediate buffering. The diagram shows customer GET request to CloudFront, cache hit/miss routing decision, Lambda orchestration of parallel SKU lookups, and streaming response back through CloudFront edge.

Architecture diagram showing the stateless streaming solution with CloudFront connected directly to Lambda.

Architecture diagram showing the stateless streaming solution with CloudFront connected directly to Lambda

Figure 2: Stateless Streaming Architecture The new architecture eliminates the middleware cache. A high-performance stream connects the user directly to the pricing source of truth. CloudFront edge locations cache the response for 95% of traffic, while remaining requests go directly to Lambda for real-time pricing.

Implementation walkthrough

Transitioning to this new architecture required solving two specific technical constraints regarding CDN behavior and cold starts. We implemented the solution in three steps.

Step 1: Implementing the streaming handler

The core of our solution is the Node.js Lambda handler wrapped in awslambda.streamifyResponse(). This allows us to pipe data through a transformation and compression stream directly to the client as it becomes available.

We used a custom NDJSONTransform to convert pricing objects into newline-delimited JSON (NDJSON), allowing the browser to parse and render each price as it arrives rather than waiting for the complete response.

// Lambda Handler with Response Streaming
// File: lambda-handler.js

import * as awslambda from "aws-lambda";
import * as zlib from "zlib";
import { pipeline } from "stream/promises";
import { NDJSONTransform } from "./transforms/ndjson-transform.js";

// Constants
const PROCESSING_MODE = process.env.PROCESSING_MODE || "MODE_QUERYSTRING";
const MODE_QUERYSTRING = "MODE_QUERYSTRING";

// The Handler MUST be wrapped in streamifyResponse() to enable streaming
export const handler = awslambda.streamifyResponse(
  async (event, responseStream, _context) => {
    try {
      if (PROCESSING_MODE === MODE_QUERYSTRING) {
        // Set response metadata with status code and headers
        const httpResponseMetadata = {
          statusCode: 200,
          headers: {
            "Content-Type": "application/x-ndjson",
            "Content-Encoding": "gzip",
            "Cache-Control": "public, max-age=300", // 5 min cache
            "X-Custom-Header": "lambda-streaming",
          },
        };

        responseStream = awslambda.HttpResponseStream.from(
          responseStream,
          httpResponseMetadata
        );

        const ndjsonTransform = new NDJSONTransform();

        // Create gzip stream with fast compression level (Z_BEST_SPEED = Level 1)
        // Level 1 prioritizes speed over compression ratio for real-time responses
        const gzip = zlib.createGzip({
          level: zlib.constants.Z_BEST_SPEED,
        });

        // Process the request, writing to the gzip stream
        await processRequestUsingQueryString(event, ndjsonTransform, _context);

        // Pipeline: Transform → Compress → Send
        await pipeline(ndjsonTransform, gzip, responseStream);
      }

      // ... error handling
    } catch (error) {
      console.error("Lambda streaming error:", error);
      responseStream.destroy();
    } finally {
      await flushMetrics().catch(console.error);
    }
  }
);

Helper function to fan-out the requests in parallel:

// Process request: fan out SKU lookups in parallel
async function processRequestUsingQueryString(event, ndjsonTransform, context) {
  try {
    // Parse query string to extract SKU list
    const queryString = event.rawQueryString || "";
    const skus = parseCompressedQueryString(queryString);

    // Fetch pricing in parallel using Promise.all
    const pricingPromises = skus.map((sku) =>
      fetchPricingForSKU(sku).catch((err) => ({
        sku: sku.id,
        error: err.message,
      }))
    );

    const pricingResults = await Promise.all(pricingPromises);

    // Emit each result as a separate NDJSON line
    for (const result of pricingResults) {
      ndjsonTransform.write(result);
    }

    ndjsonTransform.end();
  } catch (error) {
    ndjsonTransform.destroy(error);
  }
}

The handler also uses helper functions for parsing the compressed query string (parseCompressedQueryString), fetching individual SKU prices with connection pooling (fetchPricingForSKU), and flushing metrics to Amazon CloudWatch (flushMetrics).

Key implementation details:

  • awslambda.streamifyResponse() wraps the handler so it streams data in real time instead of waiting for the full response from the pricing engine.
  • NDJSONTransform converts objects to newline-delimited JSON (one object per line)
  • GZIP (GNU zip) compression with Z_BEST_SPEED (Level 1) prioritizes speed over compression ratio
  • pipeline() handles error propagation and stream cleanup
  • Response headers include Cache-Control for CloudFront caching

Step 2: Compressing the request data into a GET request

We needed to send complex request data (30 SKUs, context metadata) to the API.

Constraint: CloudFront and standard HTTP specs treat POST requests as non-idempotent, meaning they are not cacheable by default.

Our approach: We developed a dense, compressed query string format to fit the complex request data into a standard GET request. Format: g=group1(p=SKU-A:1:p=SKU-B:2)…

This allowed us to strictly use GET requests, keeping the request URI within standard length limits (~800 bytes) while carrying the same data as a 3-4KB JSON body.

Client-Side Code: Building the Compressed Query String

// Client-side: Building the compressed query string format
// File: pricing-client.js

/**
 * Builds a compressed query string for bulk pricing requests
 * Format: g=group1(p=SKU-A:1:p=SKU-B:2:p=SKU-C:3)
 * @param {Array} skus - Array of SKU objects with { id, variant }
 * @param {Object} context - Customer context { customerId, region, sessionId }
 * @returns {string} Compressed query string
 */
function buildPricingQueryString(skus, context = {}) {
  if (!skus || skus.length === 0) {
    throw new Error("SKUs array cannot be empty");
  }

  if (skus.length > 30) {
    throw new Error("Maximum 30 SKUs per request. Split into multiple batches.");
  }

  // Build SKU portion: p=SKU-001:1:p=SKU-002:2
  const skuParts = skus
    .map((sku) => {
      const variant = sku.variant || 1;
      return `p=${sku.id}:${variant}`;
    })
    .join(":");

  // Build context portion (optional)
  let contextPart = "";
  if (context && Object.keys(context).length > 0) {
    const contextStr = Object.entries(context)
      .map(([key, value]) => `${key}=${value}`)
      .join(":");
    contextPart = `:c=${contextStr}`;
  }

  // Final format: g=group1(p=SKU-A:1:p=SKU-B:2:c=customerId=123:region=US-EAST-1)
  return `g=group1(${skuParts}${contextPart})`;
}

/**
 * Fetches pricing data with streaming NDJSON response parsing
 * Core pattern: read chunks, split by newlines, parse each line as JSON
 */
async function fetchPricingStream(skus, options = {}) {
  const queryString = buildPricingQueryString(skus);
  const url = `${options.baseUrl}?${queryString}`;
  const response = await fetch(url, {
    method: "GET",
    headers: { Accept: "application/x-ndjson" },
  });

  // Stream the response using the ReadableStream API
  const reader = response.body.getReader();
  const decoder = new TextDecoder();
  const pricingData = [];
  let buffer = "";

  while (true) {
    const { done, value } = await reader.read();
    if (done) break;

    // Decode chunk and append to buffer
    buffer += decoder.decode(value, { stream: true });

    // Split by newlines (NDJSON format: one JSON object per line)
    const lines = buffer.split("\n");

    // Keep the last incomplete line in buffer
    buffer = lines.pop() || "";

    // Parse each complete line as a JSON object
    for (const line of lines) {
      if (line.trim()) {
        const pricingObject = JSON.parse(line);
        pricingData.push(pricingObject);

        // Optional: update UI immediately as each price arrives
        if (options.onChunk) {
          options.onChunk(pricingObject);
        }
      }
    }
  }

  reader.releaseLock();
  return pricingData;
}

On page load, the client calls fetchPricingStream with up to 30 SKUs and an onChunk callback that updates each product’s DOM (Document Object Model) element as pricing chunks arrive. Helper functions handle updating individual price elements, displaying variant information, and gracefully degrading with a user-friendly message if pricing is temporarily unavailable.

Step 3: Configuring CloudFront for uncacheable requests

To allow CloudFront to cache these complex GET requests effectively, we configured a precise Cache Policy that includes all query strings and specific headers.

# Terraform: CloudFront Cache Policy Configuration
# File: cloudfront-cache-policy.tf

resource "aws_cloudfront_cache_policy" "pricing-cache-policy" {
  name = "${var.lambda_function_name}-cache-policy"

  # TTL Configuration
  default_ttl = 300  # 5 minutes
  max_ttl     = 1800 # 30 minutes
  min_ttl     = 300   # 5 minute

  parameters_in_cache_key_and_forwarded_to_origin {
    # Don't cache based on cookies (we don't use them)
    cookies_config {
      cookie_behavior = "none"
    }

    # Allowlist specific headers for cache key
    headers_config {
      header_behavior = "whitelist"
      headers {
        items = [
          "x-ecom-pricing-1",   # Custom headers (anonymized)
          "x-ecom-pricing-2",  
          "x-ecom-pricing-3"    
        ]
      }
    }

    # Include query strings in cache key
    # This verifies different SKU combinations have separate cache entries
    query_strings_config {
      query_string_behavior = "all"
    }

    # Enable automatic GZIP compression
    enable_accept_encoding_gzip = true
  }
}

# CloudFront Origin Request Policy (forward headers to Lambda)
resource "aws_cloudfront_origin_request_policy" "pricing-origin-policy" {
  name = "${var.lambda_function_name}-origin-policy"

  headers_config {
    header_behavior = "whitelist"
    headers {
      items = [
        "x-ecom-pricing-1",
        "x-ecom-pricing-2",
        "x-ecom-pricing-3"
      ]
    }
  }

  query_strings_config {
    query_string_behavior = "all"
  }

  cookies_config {
    cookie_behavior = "none"
  }
}

The CloudFront distribution itself is configured with HTTPS-only viewer protocol, the cache policy and origin request policy as shown in the preceding section, and points to the Lambda as its origin through HTTPS.

Cache policy highlights:

  • 5-minute default TTL balances freshness and cache efficiency
  • Query strings included in cache key (different SKU combos = separate cache entries)
  • Header allowlisting allows custom pricing variants
  • Automatic GZIP compression reduces bandwidth
  • 5–30 minute TTL range provides flexibility for different content

Performance optimization results

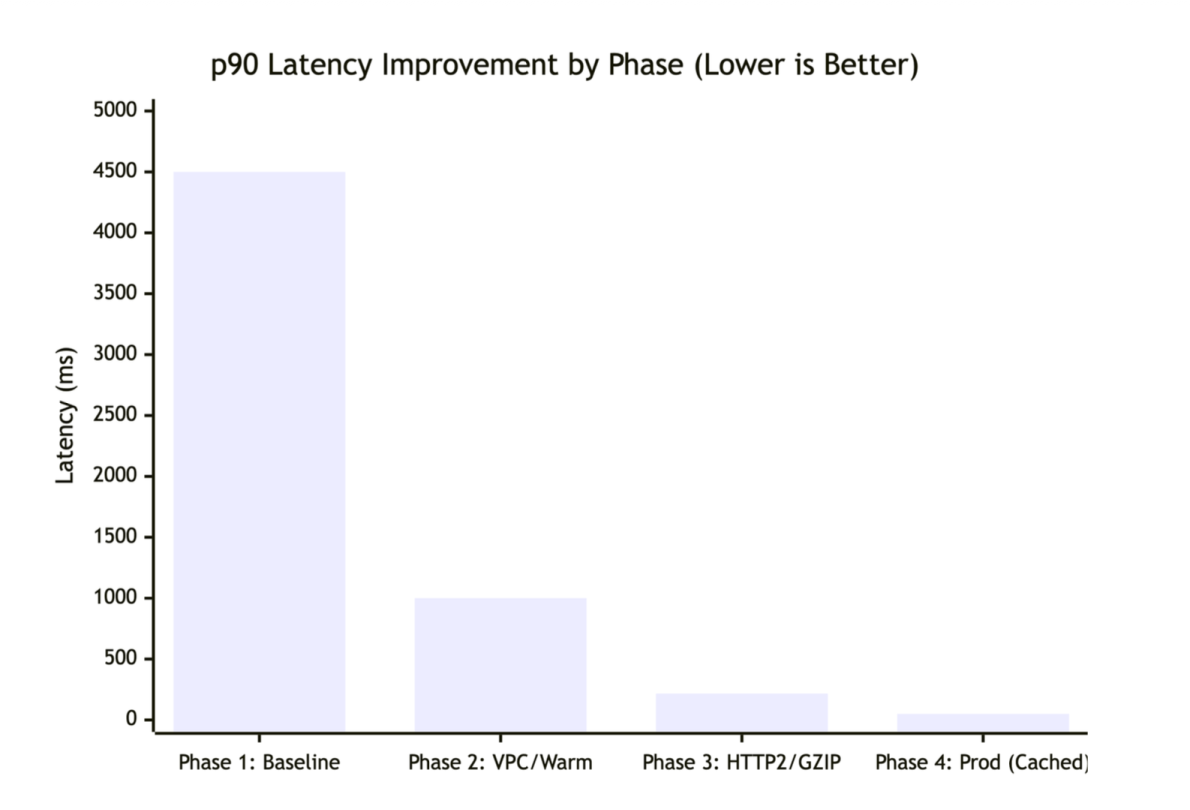
We optimized the system through four distinct phases, testing each configuration with K6 load test scripts (500 concurrent users, 30 items per request) to simulate high-traffic events like Black Friday.

Phase 1: The baseline (Global VPN)

We tested our initial proof-of-concept with the default network configuration, where all outbound traffic (including requests to AWS services like Lambda) was routed through a global VPN, forcing traffic onto the public network and back into the AWS backbone, adding unnecessary network hops and delays. The Lambda used a standard buffered response with no compression. The results were suboptimal (4,500ms P90) because connection overhead dominated the request.

  • DNS resolution: approximately 50 ms
  • TCP handshake: approximately 100 ms
  • TLS negotiation: approximately 150 ms
  • Total connection overhead: approximately 300 ms per call

This overhead created a massive bottleneck for latency before business logic even ran.

Phase 2: Amazon VPC Peering and warm starts

To remove the network penalty, we acted on two fronts:

  • First: Moved the Lambda inside an Amazon Virtual Private Cloud (Amazon VPC) peered directly to the pricing origin, cutting DNS and TLS overhead to near zero for internal calls.
  • Second: Enabled Provisioned Concurrency for Lambda to remove the 500–1000 ms cold start latency.

With these changes, P90 latency dropped to 1,000 ms, a 4.5x improvement, but still not real-time enough.

Phase 3: HTTP/2 and GZIP compression

The remaining bottleneck was the sheer size of the data transfer. We targeted two optimizations:

  • HTTP/2 Multiplexing: Enabled HTTP/2 multiplexing to reuse a single TCP connection for the 30 parallel SKU lookups, saving seconds of cumulative handshake time.
  • GZIP Compression: Applied GZIP compression (Level 1 / Z_BEST_SPEED), which reduced the response size by 76 percent (170KB → 40KB).

These two optimizations brought P90 latency down to 218 ms.

Phase 4: Production (edge caching)

In the final phase, we layered CloudFront edge caching on top of the optimized Lambda. Because we had successfully converted our request data to a GET request (Step 2), we could now cache the computed prices for 95 percent of incoming traffic.The final P90 latency landed at 50 ms.In practice, the 95 percent cache hit ratio means only 1 in 20 requests actually invokes the Lambda function; the rest are served directly from CloudFront edge locations closest to the customer. During peak events like Black Friday, this translates to millions of requests served at edge speed without touching the origin, keeping both latency and compute costs minimal.

Performance metrics table

Metric Phase 1 (Baseline) Phase 2 (VPC) Phase 3 (HTTP/2) Phase 4 (Production)
P50 Latency 1,670 ms 501 ms 176 ms 35 ms
P90 Latency 4,500 ms 1,000 ms 218 ms 50 ms
P99 Latency 5,100 ms 2,400 ms 500 ms 150 ms
Cache Hit Ratio <1% <1% <1% 95%
Response Size 170 KB 170 KB 40 KB 40 KB
Concurrent Users 500 500 500 500
P90 Improvement vs Baseline 1x 4.5x 20x 90x

The following chart shows P90 latency improvements across each optimization phase.

Latency improvements across four optimization phases

Latency improvements across four optimization phases.

K6 load test configuration:

// A sample K6 load test script
import http from 'k6/http';
import { check } from 'k6';

export let options = {
  stages: [
    { duration: '2m', target: 100 },  // Ramp up
    { duration: '5m', target: 500 },  // Stay at 500 concurrent users
    { duration: '2m', target: 0 },    // Ramp down
  ],
  thresholds: {
    http_req_duration: ['p(90)<100', 'p(99)<500'], // P90 < 100ms, P99 < 500ms
  },
};

export default function () {
  const url = 'https://api.example.com/pricing?g=group1(p=SKU-001:1:p=SKU-002:2:...)';
  const res = http.get(url);
  
  check(res, {
    'status is 200': (r) => r.status === 200,
    'response has content': (r) => r.body.length > 0,
  });
}

Resilience, scale, and security considerations

Beyond latency, we designed the system to handle failure gracefully, scale under load, and protect data in transit.

Batching limits

The 30-item limit per request is intentional. If a page requires more (for example, 50 items), the client logic splits them into multiple parallel batches.–We chose 30 because of the following:

  • Lambda execution time under 5 seconds
  • Prevents timeout issues during high latency
  • Balances parallel requests vs. Lambda concurrency limits
  • Typical product listing pages show 20–30 items
async function fetchLargePricingBatch(skus) {
  const BATCH_SIZE = 30;
  const batches = [];

  // Split into 30-item chunks
  for (let i = 0; i < skus.length; i += BATCH_SIZE) {
    batches.push(skus.slice(i, i + BATCH_SIZE));
  }

  // Fetch all batches in parallel
  const results = await Promise.all(
    batches.map((batch) =>
      fetchPricingStream(batch, { timeout: 30000 })
    )
  );

  // Flatten results
  return results.flat();
}

Partial failures

The streaming architecture is resilient. If pricing for one item fails, the stream doesn’t crash; it continues processing the remaining items, so the user still sees a mostly complete page.

Partial failure handling:

async function processRequestUsingQueryString(event, ndjsonTransform, context) {
  const skus = parseCompressedQueryString(event.rawQueryString);

  for (const sku of skus) {
    try {
      const pricing = await fetchPricingForSKU(sku);
      ndjsonTransform.write(pricing);
    } catch (error) {
      // Emit error object but continue processing other SKUs
      ndjsonTransform.write({
        sku: sku.id,
        variant: sku.variant,
        error: error.message,
        timestamp: new Date().toISOString(),
      });
    }
  }

  ndjsonTransform.end();
}

Data protection

  • While constructing the query string on the client exposes the request structure, this data (SKUs, variants) is already public. The actual pricing logic and business rules remain securely protected within the Pricing Engine.
  • Data in transit encrypted with TLS 1.3.
  • Amazon VPC endpoint connection to pricing engine (no internet exposure).
  • No sensitive data logged (PII, pricing algorithms excluded).
  • CloudTrail logs API calls for audit trail.

Conclusion

Stale pricing forces engineering teams to choose between freshness and scale. With the Data Aggregation pattern, we attempted to maintain both but compromised on data integrity due to the lag inherent in scheduled synchronization.By using AWS Lambda Response Streaming and Amazon CloudFront, we removed the need for a synchronization layer entirely. The result is a system that delivers the 50 ms latency required for a smooth user experience while supporting price consistency between the product page and checkout.

Beyond performance, this architecture significantly reduced operational footprint: compute fleet shrank from over 100 auto-scaled instances during peak events to only 5–10 Lambda functions, lowering maintenance and operational costs. This outcome was the result of close collaboration between Samsung’s ecommerce engineering team, our AWS Technical Account Manager (TAM), and the Lambda and CloudFront service teams, who helped architect the solution, review design decisions, and guide Samsung through production readiness. This technique applies to similar high-traffic data aggregation scenarios: product catalogs, inventory systems, recommendation engines, or services that combine multiple backend responses in real-time.

To get started, identify your highest-latency aggregation endpoints, evaluate whether your request data can be converted to cacheable GET requests and implement Lambda Response Streaming for a single endpoint before migrating your full API

Resources:AWS Lambda Response Streaming documentationLambda Response Streaming tutorialAmazon CloudFront Developer GuideCloudFront cache policies

Learn more

For more on the concepts and technologies discussed in this post:


About the authors

AWS Weekly Roundup: Claude Opus 4.6 in Amazon Bedrock, AWS Builder ID Sign in with Apple, and more (February 9, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-opus-4-6-in-amazon-bedrock-aws-builder-id-sign-in-with-apple-and-more-february-9-2026/

Here are the notable launches and updates from last week that can help you build, scale, and innovate on AWS.

Last week’s launches
Here are the launches that got my attention this week.

Let’s start with news related to compute and networking infrastructure:

  • Introducing Amazon EC2 C8id, M8id, and R8id instances: These new Amazon EC2 C8id, M8id, and R8id instances are powered by custom Intel Xeon 6 processors. These instances offer up to 43% higher performance and 3.3x more memory bandwidth compared to previous generation instances.
  • AWS Network Firewall announces new price reductions: The service has added the hourly and data processing discounts on NAT Gateways that are service-chained with Network Firewall secondary endpoints. Additionally, AWS Network Firewall has removed additional data processing charges for Advanced Inspection, which enables Transport Layer Security (TLS) inspection of encrypted network traffic.
  • Amazon ECS adds Network Load Balancer support for Linear and Canary deployments: Applications that commonly use NLB, such as those requiring TCP/UDP-based connections, low latency, long-lived connections, or static IP addresses, can take advantage of managed, incremental traffic shifting natively from ECS when rolling out updates.
  • AWS Config now supports 30 new resource types: These range across key services including Amazon EKS, Amazon Q, and AWS IoT. This expansion provides greater coverage over your AWS environment, enabling you to more effectively discover, assess, audit, and remediate an even broader range of resources.
  • Amazon DynamoDB global tables now support replication across multiple AWS accounts: DynamoDB global tables are a fully managed, serverless, multi-Region, and multi-active database. With this new capability, you can replicate tables across AWS accounts and Regions to improve resiliency, isolate workloads at the account level, and apply distinct security and governance controls.
  • Amazon RDS now provides an enhanced console experience to connect to a database: The new console experience provides ready-made code snippets for Java, Python, Node.js, and other programming languages as well as tools like the psql command line utility. These code snippets are automatically adjusted based on your database’s authentication settings. For example, if your cluster uses IAM authentication, the generated code snippets will use token-based authentication to connect to the database. The console experience also includes integrated CloudShell access, offering the ability to connect to your databases directly from within the RDS console.

Then, I noticed three news items related to security and how you authenticate on AWS:

  • AWS Builder ID now supports Sign in with Apple: AWS Builder ID, your profile for accessing AWS applications including AWS Builder Center, AWS Training and Certification, AWS re:Post, AWS Startups, and Kiro, now supports sign-in with Apple as a social login provider. This expansion of sign-in options builds on the existing sign-in with Google capability, providing Apple users with a streamlined way to access AWS resources without managing separate credentials on AWS.
  • AWS STS now supports validation of select identity provider specific claims from Google, GitHub, CircleCI and OCI: You can reference these custom claims as condition keys in IAM role trust policies and resource control policies, expanding your ability to implement fine-grained access control for federated identities and help you establish your data perimeters. This enhancement builds upon IAM’s existing OIDC federation capabilities, which allow you to grant temporary AWS credentials to users authenticated through external OIDC-compatible identity providers.
  • AWS Management Console now displays Account Name on the Navigation bar for easier account identification: You now have an easy way to identify your accounts at a glance. You can now quickly distinguish between accounts visually using the account name that appears in the navigation bar for all authorized users in that account.
  • Amazon CloudFront announces mutual TLS support for origins: Now with origin mTLS support, you can implement a standardized, certificate-based authentication approach that eliminates operational burden. This enables organizations to enforce strict authentication for their proprietary content, ensuring that only verified CloudFront distributions can establish connections to backend infrastructure ranging from AWS origins and on-premises servers to third-party cloud providers and external CDNs.

Finally, there is not a single week without news around AI :

  • Claude Opus 4.6 now available in Amazon Bedrock: Opus 4.6 is Anthropic’s most intelligent model to date and a premier model for coding, enterprise agents, and professional work. Claude Opus 4.6 brings advanced capabilities to Amazon Bedrock customers, including industry-leading performance for agentic tasks, complex coding projects, and enterprise-grade workflows that require deep reasoning and reliability.
  • Structured outputs now available in Amazon Bedrock: Amazon Bedrock now supports structured outputs, a capability that provides consistent, machine-readable responses from foundation models that adhere to your defined JSON schemas. Instead of prompting for valid JSON and adding extra checks in your application, you can specify the format you want and receive responses that match it—making production workflows more predictable and resilient.

Upcoming AWS events
Check your calendars so that you can sign up for this upcoming event:

AWS Community Day Romania (April 23–24, 2026): This community-led AWS event brings together developers, architects, entrepreneurs, and students for more than 10 professional sessions delivered by AWS Heroes, Solutions Architects, and industry experts. Attendees can expect expert-led technical talks, insights from speakers with global conference experience, and opportunities to connect during dedicated networking breaks, all hosted at a premium venue designed to support collaboration and community engagement.

If you’re looking for more ways to stay connected beyond this event, join the AWS Builder Center to learn, build, and connect with builders in the AWS community.

Check back next Monday for another Weekly Roundup.

— seb

Implementing HTTP Strict Transport Security (HSTS) across AWS services

Post Syndicated from Abhishek Avinash Agawane original https://aws.amazon.com/blogs/security/implementing-http-strict-transport-security-hsts-across-aws-services/

Modern web applications built on Amazon Web Services (AWS) often span multiple services to deliver scalable, performant solutions. However, customers encounter challenges when implementing a cohesive HTTP Strict Transport Security (HSTS) strategy across these distributed architectures.

Customers face fragmented security implementation challenges because different AWS services require distinct approaches to HSTS configuration, leading to inconsistent security postures.Applications using Amazon API Gateway for APIs, Amazon CloudFront for content delivery, and Application load balancers for web traffic lack unified HSTS policies, leading to complex multi-service environments. Security scanners flag missing HSTS headers, but remediation guidance is scattered across service-specific documentation, causing security compliance gaps.

HSTS is a web security policy mechanism that protects websites against protocol downgrade attacks and cookie hijacking. When properly implemented, HSTS instructs browsers to interact with applications exclusively through HTTPS connections, providing critical protection against man-in-the-middle issues.

This post provides a comprehensive approach to implementing HSTS across key AWS services that form the foundation of modern cloud applications:

  1. Amazon API Gateway: Secure REST and HTTP APIs with centralized header management
  2. Application Load Balancer: Infrastructure-level HSTS enforcement for web applications
  3. Amazon CloudFront: Edge-based security header delivery for global content

By following the implementation steps in this post, you can establish a unified HSTS strategy that aligns with AWS Well-Architected Framework security principles while maintaining optimal application performance.

Understanding HSTS security and its benefits

HTTP Strict Transport Security is a web security policy mechanism that helps protect websites against protocol downgrade attacks and cookie hijacking. When a web server declares HSTS policy through the Strict-Transport-Security header, compliant browsers automatically convert HTTP requests to HTTPS for the specified domain. This enforcement occurs at the browser level, providing protection even before the initial request reaches your infrastructure.

HSTS enforcement applies specifically to web browser clients. Most programmatic clients (such as SDKs, command line tools, or application-to-application communication) don’t enforce HSTS policies. For comprehensive security, configure your applications and infrastructure to only use HTTPS connections regardless of client type rather than relying solely on HSTS for protocol enforcement.

HTTP to HTTPS redirection enforcement on the server ensures future requests reach your applications over encrypted connections. However, it leaves a security gap during the initial browser request. Understanding this gap helps explain why client-side HSTS serves as an essential security layer in modern web applications.

For example, when users access web applications, the typical flow with redirects configured is as follows:

  1. User enters example.com in their browser.
  2. Browser sends an HTTP request to http://example.com.
  3. Server responds with HTTP 301/302 redirect to https://example.com.
  4. Browser follows redirection and establishes HTTPS connection

The initial HTTP request in step 2 creates an opportunity for protocol downgrade issues. An unauthorized party positioned between the user and your infrastructure can intercept this request and respond with content that appears legitimate while maintaining an insecure connection. This technique, known as SSL stripping, can occur even when your server-side AWS infrastructure is properly configured with HTTPS redirects.

HSTS addresses this security gap by moving security enforcement to the browser level. After a browser receives an HSTS policy, it automatically converts HTTP requests to HTTPS before sending them over the network:

  1. User enters example.com in browser.
  2. Browser automatically converts to HTTPS due to stored HSTS policy.
  3. Browser sends HTTPS request directly to https://example.com.
  4. No initial HTTP request removes the opportunity for interception.

This browser-level enforcement provides protection that complements your AWS infrastructure security configurations, creating defense in depth against protocol downgrade issues.

Although current browsers warn about insecure connections, HSTS provides programmatic enforcement. This prevents unauthorized parties from exploiting the security gap because they can’t forge valid HTTPS certificates for protected domains.

The security benefits of HSTS extend beyond simple protocol enforcement. HSTS helps prevent protocol downgrade issues after HSTS policy is established in the browser. It mitigates against man-in-the-middle issues, preventing unauthorized parties from intercepting communications. It also helps prevent unauthorized session access to protect against credential theft and unintended session access.
HSTS requires HTTPS connections and removes the option to bypass certificate warnings.

This post focuses exclusively on implementing the HTTP Strict-Transport-Security header. Although the examples include additional security headers for completeness, detailed configuration of those headers is beyond the scope of this post.

Key use cases for HSTS implementation

HSTS protects scenarios that HTTP redirects miss. For example, when legacy systems serve mixed content, or when SSO flows redirect users between providers, HSTS keeps connections encrypted throughout.

Applications serving both modern HTTPS content and legacy HTTP resources face protocol downgrade risks. When users access example.com/app that loads resources from legacy.example.com, HSTS prevents browsers from making initial HTTP requests to any subdomain, eliminating the vulnerability window during resource loading.

SSO implementations redirecting users between identity providers and applications create multiple HTTP request opportunities. Due to HSTS, authentication tokens and session data remain encrypted throughout the entire SSO flow, preventing credential interception during provider redirects.

Microservices architectures using API Gateway often involve service-to-service communication and client redirects. HSTS protects API endpoints from protocol downgrade during initial client connections, which means that API keys and authentication headers are not transmitted over HTTP.

Applications using CloudFront with multiple origin servers face security challenges when origins change or fail over. HSTS prevents browsers from falling back to HTTP when accessing cached content or during origin failover scenarios, maintaining encryption even during infrastructure changes.

From an AWS Well-Architected perspective, implementing HSTS demonstrates adherence to the defense in depth principle by adding an additional layer of security at the application protocol level. This approach complements other AWS security services and features, creating a comprehensive security posture that helps to protect data both in transit and at rest.

Implementing HSTS with Amazon API Gateway

Amazon API Gateway lacks built-in features to enable HSTS for the API resources. There are several different ways to configure HSTS headers in HTTP APIs and REST APIs.
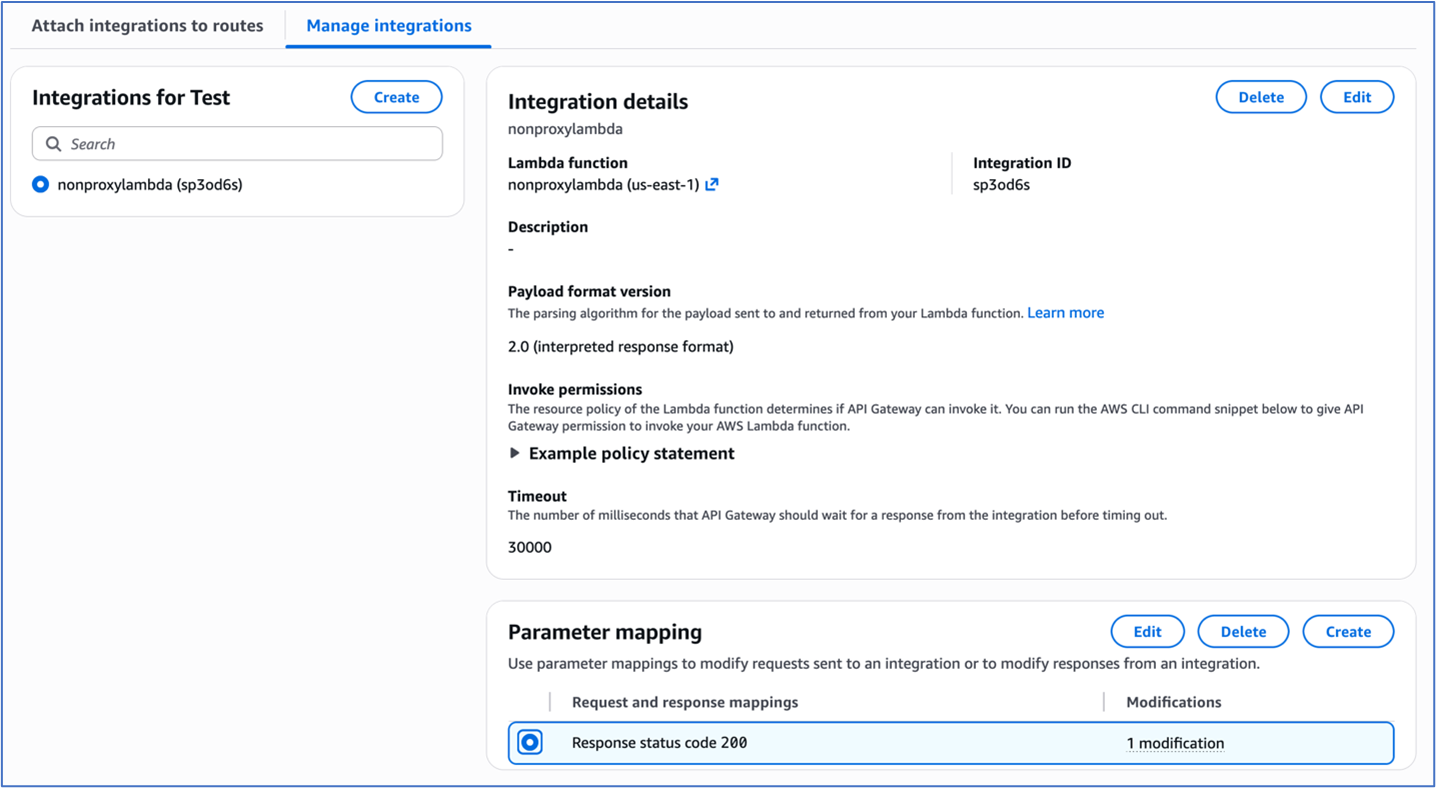
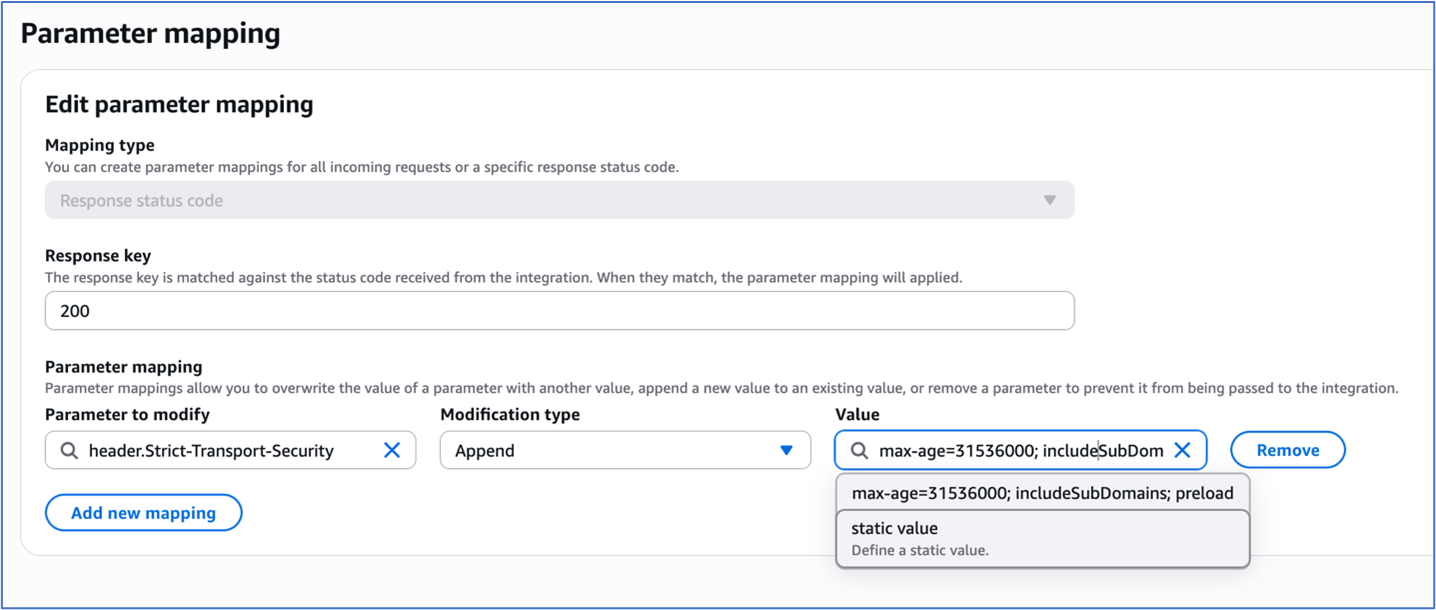
For HTTP APIs, you can configure response parameter mapping to set HSTS headers when it’s invoked using a default endpoint or custom domain.

To configure response parameter mapping:

  1. Navigate to your desired HTTP API’s route configuration in the AWS API Gateway console
  2. Access the route’s integration settings under Manage integrations tab.
Figure 1: Integration settings of the HTTP Api

Figure 1: Integration settings of the HTTP Api

  1. To configure parameter mapping, under Response key, enter 200.
  2. Under Modification type, select Append in the dropdown menu.
  3. Under “Parameter to modify”, enter header.Strict-Transport-Security
  4. Under Value, enter max-age=31536000; includeSubDomains; preload.
Figure 2: Parameter Mapping for the HTTP Api integration

Figure 2: Parameter Mapping for the HTTP Api integration

REST APIs in Amazon API Gateway offer more granular control over HSTS implementation through both proxy and non-proxy integration patterns.

For proxy integrations, the backend service assumes responsibility for HSTS header generation. For example, an AWS Lambda proxy integration must return the HSTS headers in its response as shown in the following code example:

import json 
def lambda_handler(event, context):     
	return {         
        'statusCode': 200,         
        'headers': {             
            'Strict-Transport-Security': 'max-age=31536000; includeSubDomains; preload'         
        },         
        'body': json.dumps('Secure response with HSTS headers')     
    }

For non-proxy integrations, the HSTS headers must be returned by the Rest API by implementing one of two methods, either mapping templates or method response.

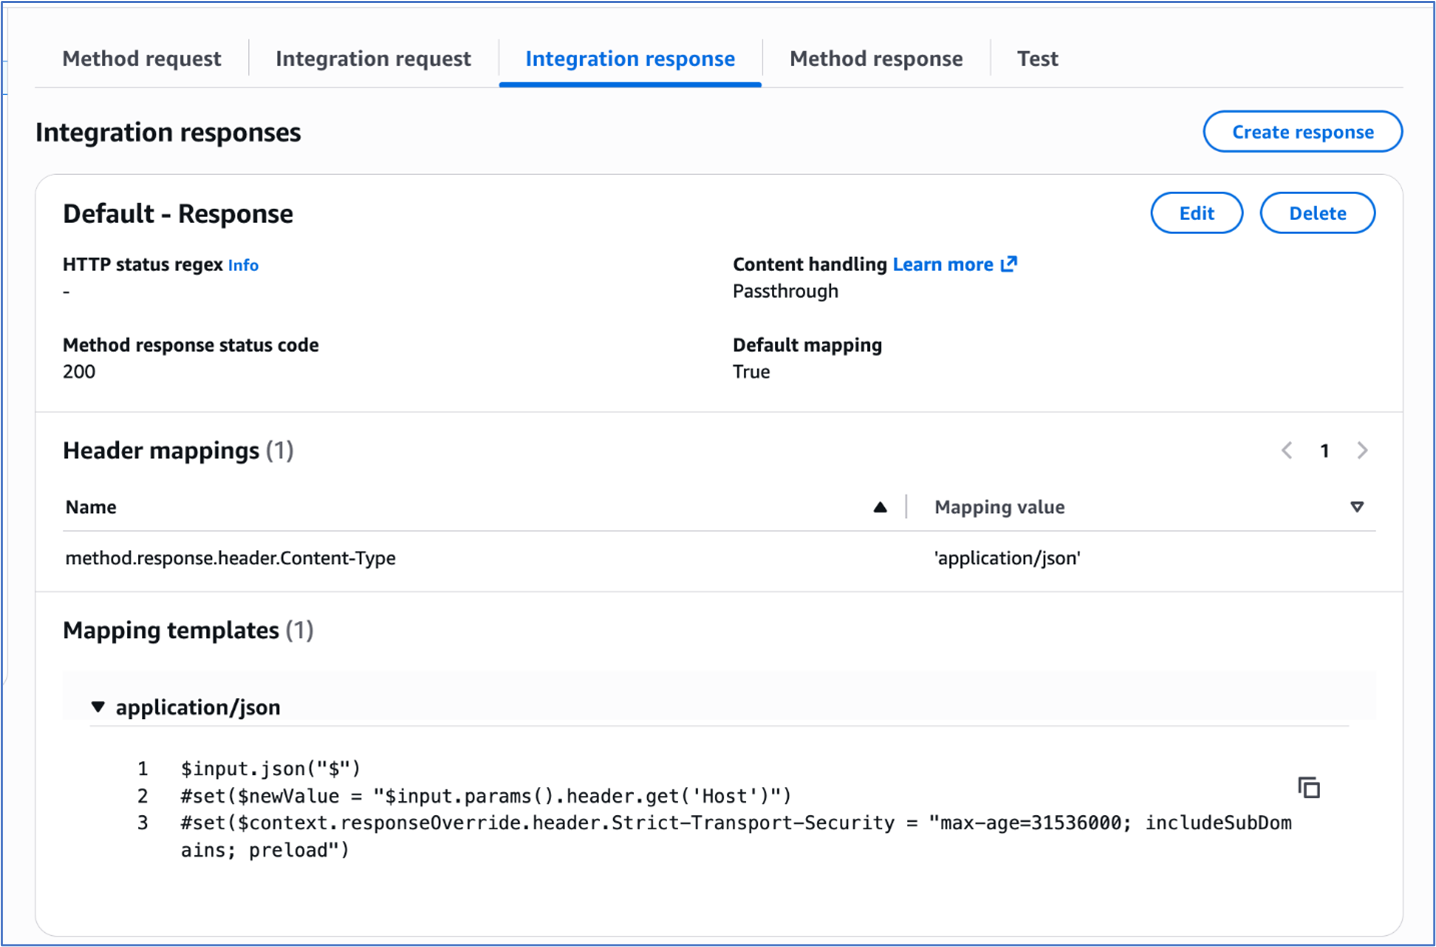
In the mapping templates method, the mapping template is used to configure the HSTS headers. The Velocity Template Language (VTL) for the mapping template is used for dynamic header generation. To implement this method:

  1. Navigate to the desired REST API and click on the method for the desired resource.
  2. Under the ‘Integration response’ tab, use the following mapping template to set the response headers:
$input.json("$") 
#set($newValue = "$input.params().header.get('Host')") 
#set($context.responseOverride.header.Strict-Transport-Security 
= "max-age=31536000; includeSubDomains; preload")

Figure 3: Adding mapping template to integration response of the Rest Api

Figure 3: Adding mapping template to integration response of the Rest Api

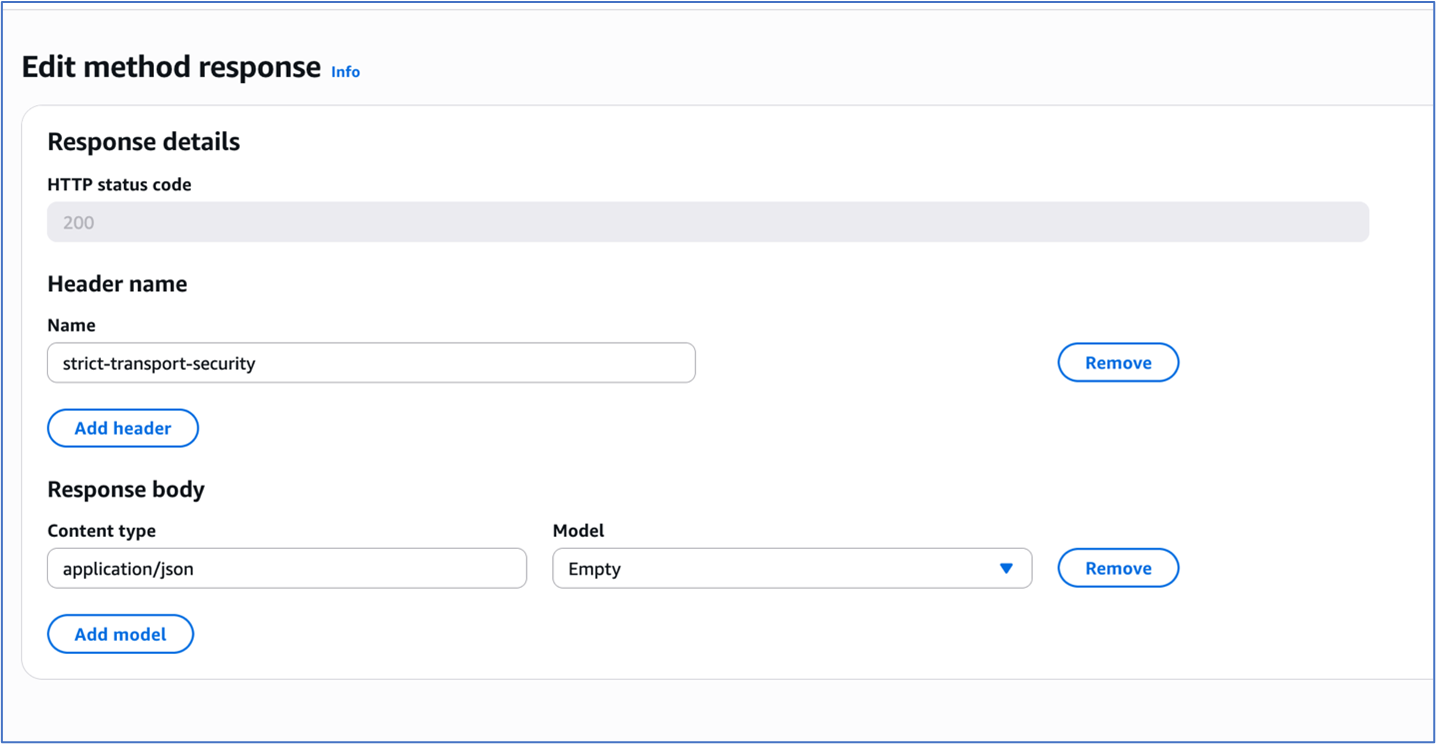
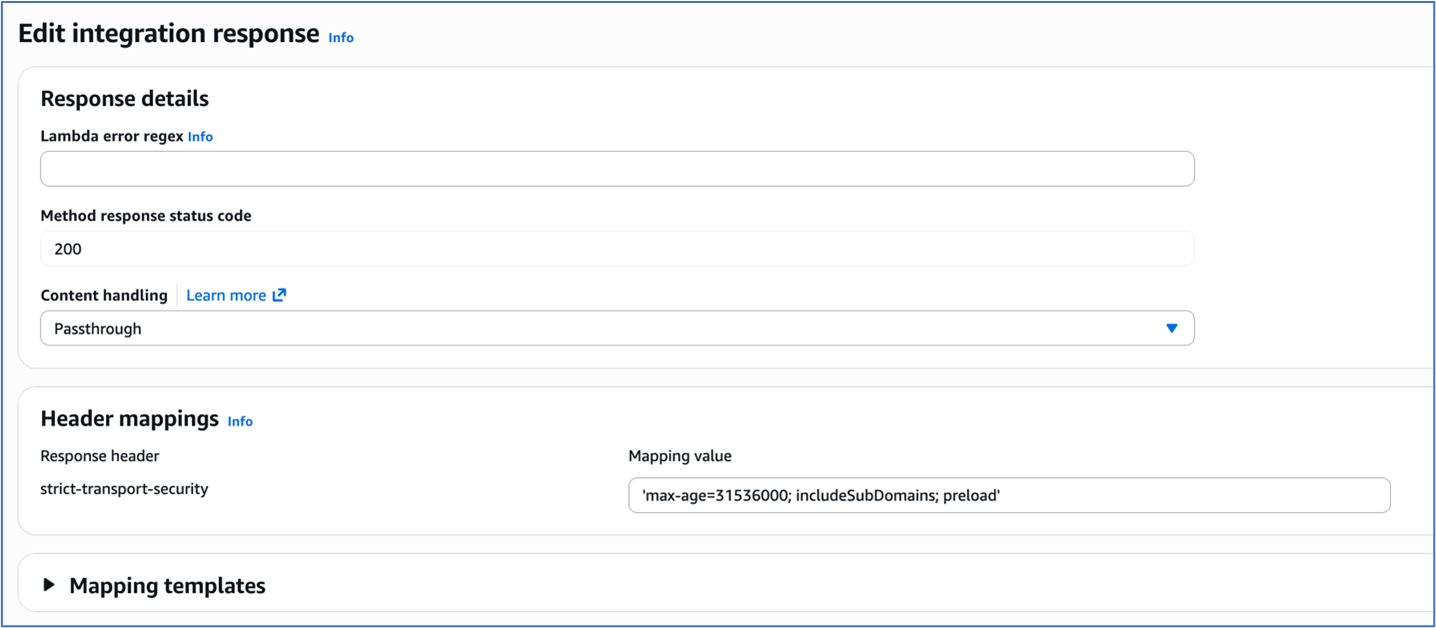
The ‘Method response’ tab provides declarative configuration through explicit header mapping in the configuration. To implement this method:

  1. Navigate to your desired REST API and select the method for the desired resource.
  2. Choose Method response and under Header name, add the HSTS header strict-transport-security.
Figure 4: Method response of the Rest Api

Figure 4: Method response of the Rest Api

3. Choose Integration response and under Header mappings, enter the HSTS header strict-transport-security. Add the Mapping value for the header as max-age=31536000; includeSubDomains; preload.

Figure 5: Integration response of the Rest Api

Figure 5: Integration response of the Rest Api

To test and validate, use the following command:

Verify HSTS implementation for both HTTP API and REST API using curl with response headers logged:

curl -i https://your-api-gateway-url.execute-
api.region.amazonaws.com/stage/resource

The expected response should include:

HTTP/2 200 

date: Tue, 20 Sep 2025 16:34:35 GMT 
content-type: application/json 
content-length: 3 
x-amzn-requestid: 76543210-9aaa-4bbb-accc-987654321012
strict-transport-security: max-age=31536000; includeSubDomains; preload 
x-amz-apigw-id: ABCDEFGHIJKLMNO

Implementing HSTS with AWS Application Load Balancers

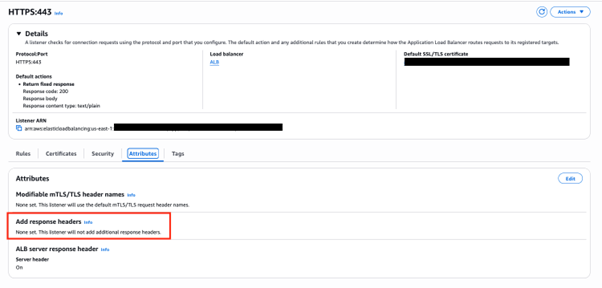
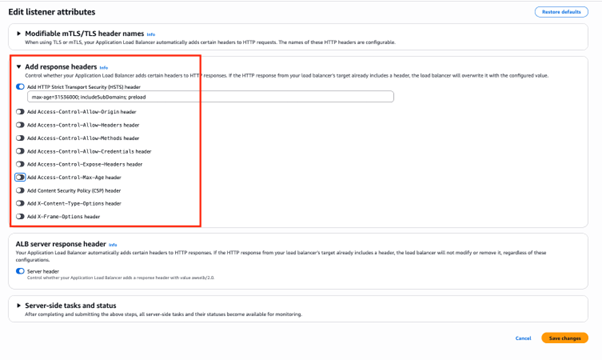
Application Load Balancers now provide built-in support for HTTP response header modification, including HSTS headers. This lets you enforce consistent security policies across all your services from a single point, reducing development effort and ensuring uniform protection regardless of which backend technologies you’re using.

Prerequisites and infrastructure requirements

Before implementing HSTS with load balancers, ensure your infrastructure meets these requirements:

  • Functional HTTPS listener – The ALB listener must be configured with HTTPS correctly.
  • Valid certificates – The ALB listener must have proper TLS certificate chain in AWS Certificate Manager and validation.
  • Application Load Balancer – The header modification feature for the ALB must be enabled for the listener since it is turned off by default.

Configuration

Application Load Balancers support direct HSTS header injection through the response header modification feature. This approach provides centralized security policy enforcement without requiring individual application configuration.

To enable HTTP header modification for your Application Load Balancer:

  1. Open the Amazon Elastic Compute Cloud (Amazon EC2) console and navigate to Load Balancers.
  2. Select your Application Load Balancer.
  3. On the Listeners and rules tab, select the HTTPS listener.
  4. On the Attributes tab, choose Edit.
    Figure 6: ALB HTTPS listener Attributes configuration

    Figure 6: ALB HTTPS listener Attributes configuration

  5. Expand the Add response headers section.
  6. Select Add HTTP Strict Transport Security (HSTS) header.
  7. To configure the header value, enter max-age=31536000; includeSubDomains; preload.
  8. Choose Save changes.
Figure 7: Add response headers in attributes configuration of the ALB HTTPS listener

Figure 7: Add response headers in attributes configuration of the ALB HTTPS listener

Header modification behavior

When ALB header modification is enabled:

  • Header addition – If the backend response doesn’t include the specified header, ALB adds it with the configured value
  • Header override – If the backend response includes the header, ALB replaces the existing value with the configured value
  • Centralized control – Responses from the load balancer include the configured security headers, ensuring consistent policy enforcement

To test and validate, use the following command:
curl -I https://my-loadbalancer-1234567890.us-west-2.elb.amazonaws.com

The following code example shows the expected response headers:

HTTP/2 200
date: Tue, 23 Sep 2025 16:34:35 GMT
strict-transport-security: max-age=31536000; includeSubDomains; preload

Header value constraints:

  • Maximum header value size – 1 KB
  • Supported characters – Alphanumeric (a-z, A-Z, 0-9) and special characters (_ :;.,/’?!(){}[]@<>=-+*#&`|~^%)
  • Empty values revert to default behavior (no header modification)

When implementing header modifications, there are several operational considerations to keep in mind. Header modification must be explicitly enabled on each listener where you want the functionality to work. Once enabled, any changes you configure will apply to all responses that come from the load balancer, affecting every request processed through that listener. Application Load Balancer performs basic input validation on the headers you configure, but it has limited capability for header-specific validation, so you should ensure your header configurations follow proper formatting and standards.

This built-in Application Load Balancer capability significantly simplifies HSTS implementation by eliminating the need for backend application modifications while providing centralized security policy enforcement across your entire application infrastructure.

Implementing HSTS with Amazon CloudFront

Amazon CloudFront provides built-in support for HTTP security headers, including HSTS, through response headers policies. This feature enables centralized security header management at the CDN edge, providing consistent policy enforcement across cached and non-cached content.

Response headers policy configuration

You can use the CloudFront response headers policy feature to configure security headers that are automatically added to responses served by your distribution. You can use managed response headers policies that include predefined values for the most common HTTP security headers. Or, you can create a custom response header policy with custom security headers and values that you can add to the required CloudFront behavior.

To configure security headers:

  1. On the CloudFront console, navigate to Policies and then Response headers.
  2. Choose Create response headers policy.
  3. Configure policy settings:
    • NameHSTS-Security-Policy
    • Description – HSTS and security headers for web applications
  4. Under Security headers, configure:
    • Strict Transport Security – Select
    • Max age – 31,536,000 seconds (1 year)
    • Preload – Select (optional)
    • IncludeSubDomains – Select (optional)
  5. Add additional security headers:

    • X-Content-Type-Options
    • X-Frame-Options – Select Origin as “SAMEORIGIN”
    • Referrer-Policy – Select “strict-origin-when-cross-origin”
    • X-XSS-Protection – Select “Enabled”, Tick “Block”
    • Choose Create.
Figure 8: Configuring response header policy for the Cloudfront distribution

Figure 8: Configuring response header policy for the Cloudfront distribution

To attach the policy to the distribution:

  1. Navigate to your CloudFront distribution.
  2. Select the Behaviors tab.
  3. Edit the default behavior (or create a new one).
  4. Under Response headers policy, select your created policy.
  5. Choose Save changes.
Figure 9: Selecting the response headers policy

Figure 9: Selecting the response headers policy

Header override behavior:
CloudFront response headers policies provide origin override functionality that controls how headers are managed between the origin and CloudFront. When origin override is enabled, CloudFront will replace existing headers that come from the origin server. Conversely, when origin override is disabled, CloudFront will only add the policy-defined headers if those same headers are not already present in the origin response, preserving the original headers from the source.

To test and validate, use the following command:

curl -I https://your-cloudfront-domain.cloudfront.net

The following code example shows the expected response headers:

HTTP/2 200 
date: Tue, 23 Sep 2025 16:34:35 GMT 
strict-transport-security: max-age=31536000; includeSubDomains; preload 
x-content-type-options: nosniff 
x-frame-options: SAMEORIGIN 
referrer-policy: strict-origin-when-cross-origin 
x-xss-protection: 1; mode=block 
x-cache: Hit from cloudfront

Using CloudFront has several advantages. It offers consistent header application across all content types and centralized security policy management. Edge-level enforcement reduces latency, and no origin server modifications are required. AWS edge locations offer global policy distribution.

Security considerations and best practices

Implementing HSTS requires careful consideration of several security implications and operational requirements.

The max-age directive determines how long browsers will enforce HTTPS-only access. The duration guidelines are as follows:

  • 300 seconds (5 minutes) – Safe for experimentation during initial testing phase.
  • 86,400 seconds (1 day) – For short-term commitment such as development environments.
  • 259,2000 seconds (30 days) – For medium-term validation such as staging environments.
  • 31,536,000 seconds (1 year) – For long-term commitment such as production environments.

We recommend that you start with shorter max-age values during initial implementation and gradually increase them as you gain confidence in your HTTPS infrastructure stability.

The includeSubDomains directive extends HSTS enforcement to all subdomains. It offers several benefits, including comprehensive protection across the entire domain hierarchy, prevention of subdomain-based attacks, and simplified security policy management.

Requirements for using this directive include:

  • Subdomains should support HTTPS to use this directive effectively.
  • Subdomains should have valid SSL certificates.
  • You must maintain a consistent security policy across domain hierarchy.

Consider implementing HSTS preloading for maximum security coverage:

Strict-Transport-Security: max-age=31536000; includeSubDomains; preload

Preloading benefits include protection for first-time visitors, browser-level enforcement before network requests, and maximizing security coverage.

The following are some preloading considerations:

  • It requires submission to browser preload lists.
  • It’s difficult to reverse because removal takes months.
  • It requires long-term commitment to HTTPS infrastructure.

For more information, see:

Conclusion

Implementing HSTS across AWS services provides a robust foundation for securing web applications against protocol downgrade attacks and enabling encrypted communications. By using the built-in capabilities of API Gateway, CloudFront, and Application Load Balancers, organizations can create comprehensive security policies that align with AWS Well-Architected Framework principles.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Abhishek Avinash Agawane

Abhishek is a Security Consultant at Amazon Web Services with more than 8 years of industry experience. He helps organizations architect resilient, secure, and efficient cloud environments, guiding them through complex challenges and large-scale infrastructure transformations. He has helped numerous organizations enhance their cloud operations through targeted optimizations, robust architectures, and best-practice implementations.

Modernization of real-time payment orchestration on AWS

Post Syndicated from Neeraj Kaushik original https://aws.amazon.com/blogs/architecture/modernization-of-real-time-payment-orchestration-on-aws/

The global real-time payments market is experiencing significant growth. According to Fortune Business Insights, the market was valued at USD 24.91 billion in 2024 and is projected to grow to USD 284.49 billion by 2032, with a CAGR of 35.4%. Similarly, Grand View Research reports that the global mobile payment market, valued at USD 88.50 billion in 2024, is expected to grow at a CAGR of 38.0% from 2025 to 2030. (Disclaimer: Third-party market research and statistics are provided for informational purposed only. AWS and IBM make no representations about the accuracy of this information.)

This rapid expansion underscores the urgency for financial institutions to modernize their payment processing infrastructure. Financial institutions often need to process high volume of transactions with near-zero latency to meet stringent service level agreements (SLAs) to support surging mobile payments volume.

However, traditional payment orchestration systems, often built on monolithic architectures, struggle to meet these demands due to latency, availability, and scalability challenges. Additionally, their reliance on on-premises infrastructure leads to higher costs and an impediment to innovation, reinforcing the need for modernization.

As sustainability becomes a priority, organizations are turning to cloud-based solutions to optimize infrastructure, reduce carbon footprints, and enhance energy efficiency. This shift provides scalability and performance, and aligns with global sustainability goals, securing the future of real-time payments.

In this post, we discuss the real-time payment orchestration framework. It uses an event-driven architecture and AWS serverless services to enhance the resiliency, efficiency, and scalability of real-time payments. By decomposing payment processing into distinct business capabilities, financial institutions can improve modularity and flexibility. Implementing tenant-based segregation helps with data isolation and security. Additionally, adopting asynchronous communication through Amazon Managed Streaming for Apache Kafka (Amazon MSK) enhances scalability and resilience.

Traditional real-time payment orchestration

Payment orchestration serves as a middleware solution, streamlining transaction processing across multiple payment methods, gateways, and financial institutions. It orchestrates key business functions such as payment authorization, payment processing, settlement and clearing, compliance and risk management, and account management for both inbound and outbound payment flows.

The following diagram depicts the high-level business capabilities supported by payment orchestrators across various payment flows, including real-time payments, digital disbursements, tax payments, wires, and more.

Payment processing system flowchart showing main components from acceptance to billing

Detailed flowchart depicting a payment processing system with multiple components. The diagram shows primary payment types at the top (including Realtime Payments, Digital Disbursement, Credit Transfer, and Peer to Peer Payments) flowing down through core processing stages including Payment Acceptance, Execution, Clearing, Reporting, Tracking, Reversals, and Billing.

Many financial institutions adopt a tenant-based approach organized by geography due to varying clearing processes, localized regulations, and transaction requirements across AWS Regions. However, without proper separation of services, teams often continue to add region-specific logic to existing services, gradually increasing their monolithic complexity and using the same infrastructure for all payment flows.

Traditional payment systems process transactions linearly, with each step waiting for the previous one to complete. However, analysis of payment workflows reveals numerous opportunities for parallel execution:

  • Sanctions screening and fraud detection – Compliance and fraud checks can run simultaneously with initial routing decisions, rather than sequentially blocking all subsequent processing
  • Payment routing and authorization requests – When basic validations are complete, routing and authorization can proceed in parallel rather than one after another
  • Payment execution and ledger updates – The actual payment execution doesn’t need to wait for ledger records to be updated—these can occur concurrently
  • Settlement, reconciliation, and tracking – These post-transaction processes can be initiated independently as soon as the primary transaction is complete

This parallel approach can dramatically improve throughput and reduce latency compared to traditional queue-based systems where operations form a sequential chain that extends processing time and creates bottlenecks.

Most legacy payment orchestration systems rely heavily on on-premises virtual machines (VMs), leading to several challenges:

  • Multi-Region support for disaster recovery and multi-tenancy resulting in significant capital expenditure and operational overhead
  • High latency and SLA issues caused by sequential message processing and delays between globally separated data centers
  • Limited reusability of payment flows as monolithic architectures require region-specific changes for local clearing mechanisms and regulations, increasing complexity and costs
  • Scalability challenges and high memory consumption due to inefficient resource utilization and execution of irrelevant logic across regions
  • Complex cross-border payment routing caused by variations in clearing rules, transaction limits, and local regulations, increasing latency and routing errors
  • Integration challenges with diverse data formats because legacy systems rely on proprietary standards (for example, ISO 20022, SWIFT MT), complicating data conversion and compliance
  • High deployment complexity for new payment flows due to monolithic architectures requiring extensive region-specific modifications, slowing time to market
  • Environmental impact and high carbon footprint from on-premises infrastructure consuming excessive energy, whereas cloud-based approaches improve efficiency

Solution overview

To overcome these challenges, the proposed architecture embraces the following design principles to build a future-ready, real-time payment orchestration solution:

  • Performance at scale – Handling over 1,000 transactions per second (TPS) with consistent low latency under varying load conditions.
  • High availability – Achieving 99.999% uptime to meet the strict requirements of financial transactions.
  • Geographic resilience – Supporting global operations with region-specific compliance while maintaining consistent performance.
  • Cost optimization – Reducing total cost of ownership through efficient resource utilization and serverless technologies.
  • Security and compliance – Supporting data protection and regulatory adherence across different jurisdictions.
  • Operational simplicity – Streamlining deployment, monitoring, and maintenance across the payment ecosystem.
  • Microservices – Decomposing payment processing into distinct business capabilities, so financial institutions can improve modularity and flexibility. This microservices-based approach allows for independent scaling and development of critical components.

The following diagram depicts the high-level solution architecture for real-time payments. The existing channels using synchronous or asynchronous APIs can be modified to use edge-optimized endpoints to reduce latency.

Event-driven payment orchestration system with pub/sub channels connecting multiple payment processing modules

Architecture diagram detailing an AWS-based payment orchestration platform utilizing event-driven principles. Features reusable components across two regions, with dedicated modules for payment initiation, execution, reconciliation, billing, and risk management. Implements pub/sub messaging patterns for inter-component communication and connects to enterprise systems including accounting, compliance, and analytics.

An event-driven architecture is used for payment orchestration, which handles communication through a pub/sub pattern. This architecture maintains persistent connections, improving performance of the end-to-end real-time payment processing.

The event-driven architecture for real-time payment processing allows multiple payment operations to occur simultaneously using different adaptors, as opposed to the traditional systems where payment processes are sequential and flow through a single pipeline. Payment events are distributed to specialized payment processor microservices based on their function (initiation, execution, tracking, settlements), enabling each to process independently without waiting for others to complete.

Because we’re transitioning from sequential processing to distributed, maintaining transaction traceability is crucial. The payment tracking adapters shown in the preceding diagram connect to enterprise analytics systems, creating a specialized layer for monitoring transactions. The pub/sub model allows for attaching correlation IDs to events, enabling systems to track related events across different topics and processing stages.

A standardized event schema serves as the foundation for this architecture, providing consistency across regional deployments while allowing for customization at the adapter level. This schema defines uniform event structures containing tenant-specific metadata and supports versioning to accommodate evolving requirements. By isolating region-specific variations to the adapter layer, the solution maintains core functionality while interfacing with diverse enterprise systems through configuration-driven customization rather than code changes.

For most payment processes, especially those with independent processing steps that can run in parallel, this architecture delivers net performance gains despite the topic switching overhead, particularly for complex transactions where multiple independent validations or processing steps are required.

Deployment on the AWS Cloud

The solution uses edge-optimized Amazon API Gateway for channels. An edge-optimized API endpoint routes requests to the nearest Amazon CloudFront Point of Presence (POP), which can help in cases where your clients are geographically distributed to enable efficient routing within each geographical region, enhancing global responsiveness by minimizing network round trips and making sure requests take the shortest possible path before transitioning from the public internet to the client network.

The following diagram illustrates the high-level solution architecture for real-time payments.

Multi-region AWS payment architecture with managed Kafka topics connecting Lambda microservices and DynamoDB storage

Comprehensive AWS payment orchestration solution implementing modern cloud-native architecture principles. Core processing logic implemented as Lambda functions covering initiation, execution, reconciliation, billing, tracking, risk management, and settlement workflows. Leverages Amazon MSK for reliable event streaming between components, with dedicated Kafka topics for each processing stage. Data persistence handled by Amazon DynamoDB, supporting cross-region operations. Architecture demonstrates AWS best practices for financial services, including regional redundancy, serverless computing, managed services, and event-driven design patterns. System integrates with external banking infrastructure and enterprise systems while maintaining separation of concerns through microservices architecture. Features built-in support for compliance monitoring, risk management, and payment tracking through specialized Lambda functions.

The solution uses Amazon MSK to implement an event-driven architecture that efficiently handles both inbound and outbound channels traffic through API requests and asynchronous message-based events. Amazon MSK communicates using a high-performance binary protocol between producers, consumers, and brokers, providing low latency and high throughput. Real-time payments are logically partitioned across multiple tenants within geographical regions—North America, EMEA, LATAM, and Asia-Pacific.

Each real-time payment tenant follows an active/active disaster recovery strategy by deploying MSK clusters across multiple AWS Regions, designed to achieve high availability and resilience. Amazon MSK offer both serverless and provisioned cluster options. The team can decide to select one or the other depending on the non-functional requirements and team expertise. Amazon MSK automatically manages partition leadership with leaders in primary Regions and followers in secondary Regions. During failover, leaders are re-elected in healthy Regions, designed to help maintain processing capabilities during regional incidents. Sticky partitioning uses consistent hashing for deterministic routing, and cooperative rebalancing enables efficient failover. Multi-AZ deployment provides zone redundancy and isolated clusters per Region for data sovereignty compliance through programmatic AWS Identity and Access Management (IAM) and virtual private cloud (VPC) boundaries.

To support seamless cross-Region replication and maintain message continuity, Amazon MSK Replicator—a fully managed feature of Amazon MSK—is used to replicate topics and synchronize consumer group offsets across clusters. MSK Replicator simplifies the process of building multi-Region Kafka applications by not needing custom code, open-source tool configuration, or infrastructure management. It automatically provisions and scales the necessary resources, so teams can focus on business logic while only paying for the data being replicated. In the event of a regional outage or failover, traffic can be automatically redirected to a healthy Region without data loss or service disruption, providing near-zero Recovery Time Objectives (RTOs) and uninterrupted operations for downstream services such as payment processors and audit trail consumers.

In addition to regional redundancy, the architecture uses an event-driven architecture to enable parallel and decoupled processing of payment transactions. Events such as transaction initiation, validation, and settlement are emitted asynchronously and consumed by various microservices independently, which drastically reduces end-to-end latency.

To process these events at scale, the architecture can use AWS Lambda, Amazon Elastic Container Service (Amazon ECS), or Amazon Elastic Kubernetes Service (Amazon EKS) depending upon non-functional requirements. Automatic scaling responds to Amazon CloudWatch metrics, and exponential backoff retry logic with dead-letter queues (DLQs) handles throttling scenarios. Circuit breakers prevent cascade failures during high error rates.

One of the key benefits of the solution is the reusability of payment flows across different regions. Although each region has its own unique compliance requirements and settlement rules, the core functionalities of real-time payments (payment authorization, payment processing, settlement and clearing) are largely similar. This reusability enables rapid deployment of payment solutions across new regions without rearchitecting the entire system. For example, the real-time payment system in the US and UK might share similar business logic for real-time gross settlement but differ in the clearing and compliance requirements. The solution treats these as bounded contexts within the microservices architecture, providing flexibility while making sure each region can handle its own specific rules and regulations.

Sustainability

AWS relentlessly innovates its infrastructure design, build, and operations to make progress towards net-zero carbon by 2040 and being water positive by 2030. Amazon MSK with AWS Graviton based instances use up to 60% less energy than comparable M5 instances, helping you achieve your sustainability goals. Lambda is inherently sustainable by design. Its serverless model makes sure compute resources are only used when needed, drastically reducing idle infrastructure and wasted energy. Instead of keeping always-on servers for infrequent tasks, Lambda provisions compute power just-in-time, achieving near-zero idle capacity.

Security and compliance in financial services

Given the sensitive nature of payment transactions and financial data, you should apply the security controls required to meet financial regulations such as AWS PCI DSS and AWS Federal Information Processing Standard (FIPS) 140-3 according to your organization’s needs.

The solution should incorporate multi-layered security controls, continuous monitoring, and automated compliance auditing to meet the rigorous expectations of banking regulators and internal risk teams. For more information, refer to Security Guidance.

Conclusion

The modernization of payment orchestration systems using an event-driven architecture and AWS serverless technologies marks a significant advancement in meeting the demands of today’s rapidly evolving financial services landscape. This solution addresses the key challenges faced by traditional payment systems while delivering substantial benefits in performance, scalability, cost optimization, global resilience, sustainability, and compliance. By using cutting-edge cloud technologies and robust security controls, financial institutions can now build a future-ready foundation that adapts to evolving business needs while maintaining the highest standards of performance, security, and reliability. As the real-time payments market continues its explosive growth, this modern architecture provides a solution that meets today’s demands and is also well-positioned to support tomorrow’s payment innovations. Organizations looking to modernize their payment infrastructure can use this blueprint to accelerate their digital transformation journey, supporting sustainable, secure, and efficient payment processing at scale in an increasingly competitive global marketplace.

The architecture presented here is for reference purposes only. IBM will work closely with you to deploy the solution in accordance with industry standards and compliance requirements.For additional resources, refer to:

IBM Consulting is an AWS Premier Tier Services Partner that helps customers who use AWS to harness the power of innovation and drive their business transformation. They are recognized as a Global Systems Integrator (GSI) for over 22 competencies, including Financial Services Consulting. For additional information, please contact an IBM Representative.

AWS Weekly Roundup: Strands Agents 1M+ downloads, Cloud Club Captain, AI Agent Hackathon, and more (September 15, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-strands-agents-1m-downloads-cloud-club-captain-ai-agent-hackathon-and-more-september-15-2025/

Last week, Strands Agents, AWS open source for agentic AI SDK just hit 1 million downloads and earned 3,000+ GitHub Stars less than 4 months since launching as a preview in May 2025. With Strands Agents, you can build production-ready, multi-agent AI systems in a few lines of code.

We’ve continuously improved features including support for multi-agent patterns, A2A protocol, and Amazon Bedrock AgentCore. You can use a collection of sample implementations to help you get started with building intelligent agents using Strands Agents. We always welcome your contribution and feedback to our project including bug reports, new features, corrections, or additional documentation.

Here is the latest research article of Amazon Science about the future of agentic AI and questions that scientists are asking about agent-to-agent communications, contextual understanding, common sense reasoning, and more. You can understand the technical topic of agentic AI with with relatable examples, including one about our personal behaviors about leaving doors open or closed, locked or unlocked.

Last week’s launches
Here are some launches that got my attention:

  • Amazon EC2 M4 and M4 Pro Mac instances – New M4 Mac instances offer up to 20% better application build performance compared to M2 Mac instances, while M4 Pro Mac instances deliver up to 15% better application build performance compared to M2 Pro Mac instances. These instances are ideal for building and testing applications for Apple platforms such as iOS, macOS, iPadOS, tvOS, watchOS, visionOS, and Safari.
  • LocalStack integration in Visual Studio Code (VS Code) – You can use LocalStack to locally emulate and test your serverless applications using the familiar VS Code interface without switching between tools or managing complex setup, thus simplifying your local serverless development process.
  • AWS Cloud Development Kit (AWS CDK) Refactor (Preview) –You can rename constructs, move resources between stacks, and reorganize CDK applications while preserving the state of deployed resources. By using AWS CloudFormation’s refactor capabilities with automated mapping computation, CDK Refactor eliminates the risk of unintended resource replacement during code restructuring.
  • AWS CloudTrail MCP Server – New AWS CloudTrail MCP server allows AI assistants to analyze API calls, track user activities, and perform advanced security analysis across your AWS environment through natural language interactions. You can explore more AWS MCP servers for working with AWS service resources.
  • Amazon CloudFront support for IPv6 origins – Your applications can send IPv6 traffic all the way to their origins, allowing them to meet their architectural and regulatory requirements for IPv6 adoption. End-to-end IPv6 support improves network performance for end users connecting over IPv6 networks, and also removes concerns for IPv4 address exhaustion for origin infrastructure.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Here are some additional news items that you might find interesting:

  • A city in the palm of your hand – Check out this interactive feature that explains how our AWS Trainium chip designers think like city planners, optimizing every nanometer to move data at near light speed.
  • Measuring the effectiveness of software development tools and practices – Read how Amazon developers that identified specific challenges before adopting AI tools cut costs by 15.9% year-over-year using our cost-to-serve-software framework (CTS-SW). They deployed more frequently and reduced manual interventions by 30.4% by focusing on the right problems first.
  • Become an AWS Cloud Club Captain – Join a growing network of student cloud enthusiasts by becoming an AWS Cloud Club Captain! As a Captain, you’ll get to organize events and building cloud communities while developing leadership skills. Application window is open September 1-28, 2025.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events as well as AWS re:Invent and AWS Summits:

  • AWS AI Agent Global Hackathon – This is your chance to dive deep into our powerful generative AI stack and create something truly awesome. From September 8 to October 20, you have the opportunity to create AI agents using AWS suite of AI services, competing for over $45,000 in prizes and exclusive go-to-market opportunities.
  • AWS Gen AI Lofts – You can learn AWS AI products and services with exclusive sessions and meet industry-leading experts, and have valuable networking opportunities with investors and peers. Register in your nearest city: Mexico City (September 30–October 2), Paris (October 7–21), London (Oct 13–21), and Tel Aviv (November 11–19).
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Aotearoa and Poland (September 18), South Africa (September 20), Bolivia (September 20), Portugal (September 27), Germany (October 7), and Hungary (October 16).

You can browse all upcoming AWS events and AWS startup events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Channy

Accessing private Amazon API Gateway endpoints through custom Amazon CloudFront distribution using VPC Origins

Post Syndicated from Napoleone Capasso original https://aws.amazon.com/blogs/compute/accessing-private-amazon-api-gateway-endpoints-through-custom-amazon-cloudfront-distribution-using-vpc-origins/

Organizations can use Amazon CloudFront Virtual Private Cloud (VPC) Origins to deliver content from applications hosted in private subnets within Amazon VPC. Network traffic flows between Amazon CloudFront and Application Load Balancers (ALBs), Network Load Balancers (NLBs), or Amazon Elastic Compute Cloud (Amazon EC2) instances deployed within private subnets. This means that Amazon CloudFront can access both public and private Amazon Web Services (AWS) resources seamlessly.

This post demonstrates how you can connect CloudFront with a Private REST API in Amazon REST API Gateway using a VPC origin.

Overview

Organizations looking to enhance their application security and performance can find several key benefits in this architecture. You can use it to keep your APIs private and access them through CloudFront, implementing more security layers such as AWS Shield Advanced, geoblocking and TLSv1.3 support along with custom cipher suites. You can use this approach to engage the global CloudFront content delivery network while maintaining more control over the distribution.

Furthermore, you can enhance security controls through the built-in features of CloudFront, such as AWS WAF integration, custom SSL certificates, and field-level encryption. The VPC Origins feature eliminates any need to expose your internal resources to the public internet, which reduces your application’s potential attack surface.

Enterprises that need to maintain strict compliance requirements while delivering content globally can find this solution particularly valuable. Contain all traffic within the AWS private network to better meet your security and compliance objectives while still providing fast, reliable access to your applications.

Solution overview

You can set up CloudFront as the front door to your application and use VPC Origins integrated with an internal ALB to route traffic to Private Rest API through an execute-api VPC endpoint. All traffic between CloudFront and Private REST API remains within the AWS Private network.

The following figure provides an overview of the solution.

Figure 1: Amazon CloudFront to Private Amazon API Gateway

This diagram depicts three services running in an AWS account. The CloudFront distribution serves as the main entry point for the application. This distribution connects to an internal ALB using VPC Origins. The interface VPC endpoint execute-api is set as the target for the internal ALB to route requests to the Private Amazon API Gateway.

Solution deployment

To deploy this solution, follow the instructions in the GitHub repository and clone the repository.

The solution can be deployed in any AWS Region. Make sure to have a valid SSL certificate in AWS Certificate Manager (ACM) in the us-east-1 Region for the CloudFront distribution. All other resources must be in the same Region.

Prerequisites

For this walkthrough, the following resources are needed:

  • An Amazon VPC with at least 2 Private Subnets.
  • A Public Hosted Zone in Amazon Route 53.
  • A valid public SSL certificate in ACM in the us-east-1 Region for CloudFront and another certificate in the same Region as an ALB.
  • A custom domain name, covered by the ACM certificate for CloudFront distribution.

These are the input parameters for the solution deployment.

Walkthrough

The AWS Serverless Application Model (AWS SAM) template from the sample GitHub repository creates a secure, private networking architecture that provides controlled access to an API Gateway through CloudFront. It provisions a private API Gateway with a VPC endpoint, an internal ALB, and a CloudFront distribution. The template establishes secure communication channels by implementing private networking components, configuring SSL certificates, and setting up Route53 DNS routing. It uses custom AWS Lambda resources to dynamically manage network interfaces and security group configurations, providing a robust and flexible infrastructure for private API access, as shown in the following figure.

Figure 2: Amazon CloudFront to Private Amazon API Gateway walkthrough

Step 1: Create the CloudFront distribution and the VPC Origins

The solution creates a CloudFront distribution that enables wide range of HTTP clients by supporting HTTP2 and HTTP3, enhances your solution security by enforcing HTTPS-only traffic, and uses a custom domain with the user-provided SSL certificate.The internal ALB is configured as the origin for the CloudFront distribution, and it is created using the VPC Origins feature.

########### Cloudfront Distribution ###############
  CloudFrontDistribution:
    Type: AWS::CloudFront::Distribution
    Properties:
      DistributionConfig:
        HttpVersion: http2and3
        Comment: CloudFront Distribution with VPC Origin Integration
        Aliases: 
        - !Ref CloudFrontDomainName
        ViewerCertificate:
          AcmCertificateArn: !Ref CloudFrontCertificateARN
          MinimumProtocolVersion: TLSv1.2_2021
          SslSupportMethod: sni-only
        Origins:
        - Id: AlbOrigin
          DomainName: !GetAtt ApplicationLoadBalancer.DNSName
          VpcOriginConfig:
            OriginKeepaliveTimeout: 60
            OriginReadTimeout: 60
            VpcOriginId: !GetAtt CloudFrontVpcOrigin.Id
        Enabled: true
        DefaultCacheBehavior:
          TargetOriginId: AlbOrigin
          CachePolicyId: 83da9c7e-98b4-4e11-a168-04f0df8e2c65
          OriginRequestPolicyId: 216adef6-5c7f-47e4-b989-5492eafa07d3
          ViewerProtocolPolicy: https-only

The VPC Origins references the internal ALB, and only supports HTTPS protocol.

  ########### Cloudfront VPC Origin ###############
  CloudFrontVpcOrigin:
    Type: AWS::CloudFront::VpcOrigin
    Properties:
      VpcOriginEndpointConfig:
          Arn: !Ref ApplicationLoadBalancer
          Name: !Sub vpc-origin-${AWS::StackName}
          OriginProtocolPolicy: https-only
          OriginSSLProtocols: 
          - TLSv1.2

When the VPC Origins is created, the custom resource Lambda function adds an inbound rule to the CloudFront VPC Origin security group to allow traffic only from the CloudFront prefix list in the chosen Region.

        ec2_client.authorize_security_group_ingress(
            GroupId=cloudfront_sg_id,
            IpPermissions=[
                {
                    'IpProtocol': 'tcp',  
                    'FromPort': 443,      
                    'ToPort': 443,        
                    'PrefixListIds': [{'PrefixListId': cloudfront_prefix_id}]
                }
            ]
        )

Step 2: Create the ALB

The internal ALB is configured with an HTTPS listener using the user-provided SSL certificate. This maintains the encryption of the traffic between CloudFront and the ALB.

########### ALB Listener ###########  
  ALBListener:
    Type: AWS::ElasticLoadBalancingV2::Listener
    Properties:
      DefaultActions:
        - Type: forward
          TargetGroupArn: !Ref ALBTargetGroup
      LoadBalancerArn: !Ref ApplicationLoadBalancer
      Port: '443'
      Protocol: HTTPS
      SslPolicy: ELBSecurityPolicy-TLS-1-2-2017-01
      Certificates:
        - CertificateArn: !Ref ALBCertificateARN

The target group of the ALB points to the execute API VPC endpoint IP addresses. These IP addresses are fetched using a custom resource Lambda function.

  ########### ALB Target Group ###########
  ALBTargetGroup:
    Type: AWS::ElasticLoadBalancingV2::TargetGroup
    Properties:
      Port: 443
      Name: !Sub TargetGroup-${AWS::StackName}
      Protocol: HTTPS
      VpcId: !Ref VPCId
      Targets:
        - Id: !GetAtt GetPrivateIPs.IP0
          Port: 443
        - Id: !GetAtt GetPrivateIPs.IP1
          Port: 443
      TargetType: ip
      Matcher:
        HttpCode: '200,403'

The custom resource Lambda function fetches private IPs for given network interface IDs using the EC2 client and returns a dictionary with keys IP0 and IP1 values as the private IPs.

def fetch_interface_ips(network_interface_ids):
    """
    Fetch private IPs for given network interface IDs using ec2 client
    Returns a dictionary with keys IP0, IP1, etc. and values as the private IPs
    """
    responseData = {}
    
    # Use describe_network_interfaces instead of the resource approach
    response = ec2_client.describe_network_interfaces(
        NetworkInterfaceIds=network_interface_ids
    )
    
    for index, interface in enumerate(response['NetworkInterfaces']):
        responseData[f'IP{index}'] = interface['PrivateIpAddress']
    
    return responseData

Furthermore, the Lambda function adds an inbound rule to the internal ALB security group to allow traffic from the VPC Origin security group.

ec2_client.authorize_security_group_ingress(
            GroupId=security_group_id,
            IpPermissions=[
                {
                    'IpProtocol': 'tcp',  
                    'FromPort': 443,     
                    'ToPort': 443,  
                    'UserIdGroupPairs': [{'GroupId': cloudfront_sg_id}]
                }
            ]
        )

Step 3: Create the VPC endpoint for Private API Gateway

The execute-api VPC Endpoint is configured to route traffic from the internal ALB to the Private API Gateway. Only VPC endpoints can resolve private endpoints and route traffic securely.

  ########### execute-api VPC Endpoint ###########
  ExecuteApiVpcEndpoint:
    Type: AWS::EC2::VPCEndpoint
    Properties:
      ServiceName: !Sub "com.amazonaws.${AWS::Region}.execute-api"
      VpcId: !Ref VPCId
      SubnetIds: !Ref PrivateSubnets
      VpcEndpointType: Interface
      PrivateDnsEnabled: true
      SecurityGroupIds:
        - !Ref VpcEndpointSG 

Step 4: Create the Private API Gateway Resource Policy

The Resource Policy set up on the Private API Gateway only allows traffic from the VPC endpoint placed within the user-defined VPC.

        x-amazon-apigateway-policy:
          Version: "2012-10-17"
          Statement:
          - Effect: "Allow"
            Principal: "*"
            Action: "execute-api:Invoke"
            Resource: "execute-api:/*"
            Condition:
              StringEquals:
                aws:sourceVpce: 
                - !Ref ExecuteApiVpcEndpoint

Testing

Fetch the CloudFront URL from the Outputs section of the deployed stack and test it by using the curl command or your web browser.

curl https://{your custom domain name} 
{"message": "Hello from API GW"}

Conclusion

This post demonstrates how you can establish a secure architecture to access a Private REST API Gateway through a Private ALB, using Amazon CloudFront as the entry point for your application. The solution uses the CloudFront VPC Origins feature, a powerful capability that you can use to directly integrate CloudFront with resources that you host within your Amazon VPC. You can implement this architecture to significantly enhance your application’s security posture as you restrict access to your backend services and minimize the potential attack surface. This approach provides you with a robust and reliable method to protect your applications from unauthorized access while maintaining high availability and performance through the CloudFront global content delivery network.

Secure file sharing solutions in AWS: A security and cost analysis guide: Part 2

Post Syndicated from Swapnil Singh original https://aws.amazon.com/blogs/security/secure-file-sharing-solutions-in-aws-a-security-and-cost-analysis-guide-part-2/

As introduced in Part 1 of this series, implementing secure file sharing solutions in AWS requires a comprehensive understanding of your organization’s needs and constraints. Before selecting a specific solution, organizations must evaluate five fundamental areas: access patterns and scale, technical requirements, security and compliance, operational requirements, and business constraints. These areas cover everything from how files will be shared and what protocols are needed, to security measures, day-to-day operations, and business limitations.

See Part 1 of this series for detailed information about each of these fundamental areas and their specific considerations. Part 1 also covers solutions including AWS Transfer Family, Transfer Family web apps, and Amazon Simple Storage Service (Amazon S3) pre-signed URLs. This part continues our analysis with additional AWS file sharing solutions to help you make an informed decision based on your specific requirements.

Solutions

Let’s start by looking at the various file sharing mechanisms that AWS supports. The following table identifies the key AWS services needed for each solution, describes the security and cost implications of the solutions, and describes their complexity and protocol support capabilities.

Solution AWS services Security features Cost* Region control
CloudFront signed URLs CloudFront, Amazon S3, and Lambda Optional edge security using AWS Lambda@Edge, WAF integration, SSL/TLS, geo restrictions, and AWS Shield Standard (included automatically) Content delivery network (CDN) costs, request pricing, and data transfer fees Global service by design; origin can be AWS Region-specific
Amazon VPC endpoint service AWS PrivateLink, Amazon VPC, and Network Load Balancer (NLB) Complete network isolation, private connectivity, and multi-layer security Endpoint hourly charges, NLB costs, and data processing fees Service endpoints are strictly Region-specific; must create endpoints in each Region where access is needed
S3 Access Points Amazon S3, IAM, Amazon VPC (for VPC-specific access points)
  • Dedicated IAM policies per access point
  • VPC-only access restrictions available
  • Works with bucket policies for layered security
  • Supports PrivateLink for private network access
  • Compatible with S3 Block Public Access settings
  • No additional charge for S3 Access Points
  • Standard S3 request pricing applies
  • Data transfer fees apply based on standard S3 rates
  • Amazon VPC endpoint charges apply when using VPC endpoints with access points
  • Access points are Region-specific
  • Each access point is created in the same Region as its S3 bucket
  • Cross-Region access requires separate access points in each Region
  • VPC-specific access points are limited to the VPC’s Region

The following table shows the solutions described in Part 1.

Solution AWS services Security features Cost* Region control
AWS Transfer Family Transfer Family, Amazon S3, API Gateway, and Lambda Managed security, encryption in transit and at rest, IAM integration, and custom authentication $0.30 per hour per protocol, data transfer fees, and storage costs Can deploy to specific AWS Regions, can only transfer files to and from S3 buckets in the same Region
Transfer Family web apps Transfer Family, S3, and CloudFront Browser-based access, IAM Identity Center integration, and S3 Access Grants Pay-per-file operation, CloudFront costs, and storage costs Uses CloudFront (global) for web access, but backend components can be Region-specific
Amazon S3 pre-signed URLs S3 Time-limited URLs, IAM controls for URL generation, and HTTPS S3 request and data transfer fees Can be restricted to specific Regions
Serverless application with Amazon S3 presigned URLs S3, Lambda, and API Gateway Time-limited URLs, HTTPS, IAM controls, customizable authentication Pay per request and minimal infrastructure cost Components can be Region-specific

* Pricing information provided is based on AWS service rates at the time of publication and is intended as an estimation only. Additional costs may be incurred depending on your specific implementation and usage patterns. For the most current and accurate pricing details, please consult the official AWS pricing pages for each service mentioned.

Let’s examine each of the solutions in detail. Part 1 talked about AWS Transfer Family, Transfer Family web apps, and Amazon S3 pre-signed URLs. Here in Part 2, we explain the remaining solutions to help you make the right choice for your use case.

CloudFront signed URLs with Amazon S3

Amazon CloudFront signed URLs combine Amazon S3 storage with the global edge network of CloudFront to deliver files securely with lower latency.

CloudFront edge locations cache content geographically closer to users, which usually reduces latency and gives better performance for users. CloudFront also reduces the number of origin requests to Amazon S3. CloudFront integration with AWS Shield and AWS WAF provides options for additional security layers, helping to protect against DDoS events and unintended requests. You can use custom domains with AWS-provided or your own SSL/TLS certificates managed through AWS Certificate Manager (ACM), helping to facilitate secure connections from users to edge locations.

When a user requests a file, the system generates a signed URL using either a CloudFront key pair or a custom trusted signer (such as Lambda Edge) that includes security parameters such as IP restrictions, time windows, and custom policies. The major difference is the content distribution network (CDN) making performance faster by caching data geographically close to the user downloading it.

The built-in logging and monitoring capabilities of CloudFront provide detailed insights into content access patterns, cache hit ratios, and security events. CloudFront integrates seamlessly with Amazon S3 to support origin access identity (OAI), helping to make sure that the S3 objects can be accessed only through CloudFront and not directly through S3 APIs.

Figure 1: CloudFront signed URLs with Amazon S3 architecture

Figure 1: CloudFront signed URLs with Amazon S3 architecture

Pros

If Amazon S3 pre-signed URLs sound good, but you need higher performance at a global scale, CloudFront signed URLs are the right choice. The AWS global edge network has points of presence (POPs) all over the world, which significantly reduces latency for users and minimizes data transfer costs through caching. This architecture provides substantial cost savings for frequently accessed content, because edge locations serve cached copies without retrieving objects from the S3 origin. The integration with AWS security services offers protection against various threats, including sophisticated distributed denial of service (DDoS) events and web application issues, making it particularly suitable for public-facing file sharing applications. Choose CloudFront instead of S3 if you tend to make the same file available to many people who download it many times, such as in software distribution or documentation distribution.

The solution’s security model provides extensive flexibility in access control implementation. You can define granular permissions through custom policies, implement geo-restriction rules, and enforce IP-based access controls. The ability to use custom TLS certificates and domains maintains brand consistency while helping to facilitate secure communications. The integration with AWS WAF enables advanced request filtering and rate limiting, while detailed access logging and real-time metrics provide visibility into content delivery and security events. The solution’s support for both signed URLs and signed cookies offers flexibility in implementing various access control scenarios. Signed cookies are used when you want to provide access to multiple restricted files. For example, if you need to provide access to many files in a private directory, you can use signed cookies to avoid having to create individual signed URLs for each file. When choosing between CloudFront signed URLs (ideal for individual file access) or signed cookies (better for providing access to multiple files, like a subscriber’s content library), consider your content distribution needs and whether your clients support cookies.

Cons

If you implement CloudFront, you must develop expertise in its configuration options, including robust key management processes and secure key rotation procedures. Self-managed certificates don’t automatically renew. You must track expiration dates and make sure you renew on time, or your users will get warnings and errors when they try to download. ACM can simplify TLS certificate management and automatically renew certificates before they expire. while trusted signer workflows enhance your security posture.

Note: To create signed URLs, you need a signer. A signer is either a trusted key group that you create in CloudFront, or an AWS account that contains a CloudFront key pair.

Misconfigured web caches have many surprising and frustrating effects for users. Understanding and configuring CloudFront cache behavior is key to helping to prevent unintended content exposure or availability issues. You need to add cache invalidation to your publication workflows so that old versions are no longer available from the cache. This might introduce additional costs and operational overhead, especially in scenarios with frequent content changes. If you frequently change the content that you share, if the content is unique to an individual (such as a personalized report), or if the same content isn’t downloaded many times by many people in many locations, you won’t realize much cost savings or reduced latency from CloudFront caching. The additional complexity added by cache configuration might not be justified unless the cache is used a lot.

If you use the CloudFront global content delivery network, your content will be stored in caches in hundreds of locations around the world. ACM will store your TLS certificates for CloudFront (whether ACM is issuing them or you manage them yourself) in the us-east-1 AWS Region. Because CloudFront is a global service, it automatically distributes the certificate from the us-east-1 Region to the Regions associated with your CloudFront distribution. Caching data and keys around the world might not be acceptable if you have data sovereignty requirements to keep your data in one country.

From a cost perspective, while CloudFront can provide savings through caching, the pricing model has other variables to consider. Data transfer costs vary by Region and can be significant for large-scale distributions. If you need custom domain names and custom TLS certificates, that might introduce additional costs. Implementation expertise is needed when dealing with dynamic content or when specific origin request handling is required. CloudFront only delivers via HTTPS and HTTP protocols, so you won’t be able to use it if you require support for other file transfer protocols. CloudFront distributions provide statistics on cache hit-and-miss rates—pay attention to these because low cache hit rates mean that you’re pulling data from the origin frequently, which limits the possible cost savings.

Amazon VPC endpoint service with custom application

Amazon VPC endpoint services, powered by AWS PrivateLink, enable private connectivity between VPCs without requiring internet access, VPN connections, or direct physical connections. This solution creates a highly secure, private network path for file sharing by exposing services through Network Load Balancers (NLB) and allowing other VPCs to access them through interface endpoints. The architecture isolates the file sharing service from the public internet, operating entirely within the AWS private network infrastructure.

The best use cases for this architecture involve sharing data or distributing software around your AWS infrastructure without exposing it to the public internet.

Figure 2: Amazon VPC endpoint service architecture

Figure 2: Amazon VPC endpoint service architecture

The solution, shown in Figure 2, typically involves deploying a custom file sharing application behind an NLB in the service VPC, which is then exposed as an endpoint service. Consumer VPCs create interface endpoints to connect to this service, establishing private connectivity through the AWS backbone network. Traffic remains within the AWS network, is encrypted in transit, and is subject to security controls at both the endpoint and VPC levels. The architecture supports many TCP-based protocols, making it versatile for various file transfer requirements.

This architecture provides secure pathways for data to travel by using multiple layers, including VPC security groups, network access control lists (ACLs), endpoint policies, and the custom application’s authentication mechanisms. The built-in security features of PrivateLink are designed so that only approved AWS principals can create interface endpoints to connect to the service, while detailed VPC flow logs provide network traffic visibility.

Pros

Amazon VPC endpoint services provide complete network isolation and private connectivity that’s inaccessible from the public internet. This reduces the exposure footprint and helps meet security requirements for sensitive data transfer operations. The solution maintains private connectivity across different AWS accounts and Regions while keeping traffic within the AWS network infrastructure.

This solution also provides the most flexible protocol support. Other solutions require you to use HTTPS, AWS API calls (which are HTTPS), or one of the protocols supported by Transfer Family (such as SFTP). If you have software that uses custom protocols, and you need security controls and network isolation, this architecture provides predictable performance through dedicated network paths and supports high throughput requirements without internet bandwidth constraints. The granular control over network security through VPC security groups, network ACLs, and endpoint policies enables organizations to implement defense-in-depth strategies effectively. Additionally, the solution’s integration with AWS Organizations facilitates centralized management and governance across multiple accounts.

Cons

Setting up and maintaining VPC endpoints requires significant expertise in AWS networking, including VPC design, PrivateLink configuration, and network security controls. The initial architecture design must carefully consider IP address management, service quotas, and Regional availability to provide scalability and reliability. Organizations must also develop and maintain the custom file sharing application in addition to the VPC endpoints.

This solution has many components that incur hourly and bandwidth-related charges. Each interface endpoint incurs hourly charges and data processing fees, which can accumulate significantly in multi-VPC or multi-Region deployments. NLBs add another cost component, and you must maintain sufficient capacity for peak loads. The solution also has operational costs because of the need for specialized expertise and ongoing maintenance. Additionally, while the private connectivity model provides superior security, it can make troubleshooting more challenging and might require additional tooling for effective monitoring and diagnostics. The Regional nature of VPC endpoints might necessitate additional architecture for multi-Region deployments, potentially increasing both costs and operational overhead. This solution is most suitable when private network security considerations are the highest priority, and cost considerations are secondary.

Amazon S3 Access Points

Amazon S3 Access Points simplify managing data access at scale for applications using shared data sets on S3. Access points are named network endpoints attached to S3 buckets that streamline managing access to shared datasets. Each access point has its own AWS Identity and Access Management (IAM) policy that controls access to the data, allowing you to create custom access permissions for different applications or user groups accessing the same bucket.

The architecture uses S3 buckets with access points providing dedicated access paths to the data. Each access point has its own hostname (URL) and access policy that works in conjunction with the bucket policy. You can create access points that only allow connections from your Amazon Virtual Private Cloud (Amazon VPC) for private network access to Amazon S3 or create access points with Internet connectivity. You can use this flexibility to implement sophisticated access control patterns while maintaining a single source of truth in S3.

Figure 3: S3 Access Points with VPC endpoints

Figure 3: S3 Access Points with VPC endpoints

Pros

Amazon S3 Access Points simplify permissions management and security to accommodate multiple access patterns and use cases. For example, if an S3 bucket contains data that needs to be accessed by multiple applications, each requiring different levels of access, you can create a dedicated access point for each application with precisely the permissions it needs, rather than managing a long monolithic bucket policy.

You can implement access control workflows, such as restricting access to specific VPCs, encryption, or limit access to specific objects or prefixes. The service requires no new infrastructure management, reducing operational overhead and allowing you to focus on business logic implementation.

Access points provide a way to enforce network controls through VPC-only access points, helping to make sure that data can only be accessed from within your private network. IAM permissions management becomes more granular and straightforward to audit when each application or user group has its own access point with a dedicated policy. You can associate different access points with different network origins.

Another possible use case is when you need to provide temporary access to specific data within a bucket without modifying the bucket policy. You can create a temporary access point with the necessary permissions and delete it when the access is no longer needed.

Cons

Access points add another layer to your Amazon S3 architecture that needs to be managed and monitored. Each access point has its own Amazon Resource Name (ARN) and hostname that applications need to use instead of the bucket name, which might require changes to your application code.

There are limits to the number of access points you can create for each bucket, which might be a constraint for large-scale applications. Access points can only control access to the bucket they’re associated with, not across multiple buckets, so if your application needs to access data across buckets, you’ll need multiple access points.

When implementing this solution, you need to design your access point policies to make sure that they work correctly with your bucket policy. Think of your S3 bucket policy as the primary security framework, while access point policies act as specialized gatekeepers. These two layers of security must work in harmony. The bucket policy takes precedence. For example, if your bucket policy explicitly denies access from specific IP ranges, an access point policy can’t override this restriction. This hierarchical relationship requires strategic planning. Start by defining your broad security boundaries in the bucket policy—perhaps allowing access only from specific VPCs or requiring encryption. Then create your access point policies within these boundaries.

While Amazon S3 Access Points offer powerful flexibility, understanding their boundaries is crucial. Cross-account scenarios, common in large enterprises or partner collaborations, require careful configuration. Imagine you’re working with an external auditing firm that needs temporary access to your financial data stored in S3. Setting up a cross-account access point requires creating the access point in your account, configuring a trust policy to allow the external account, verifying that the bucket policy permits access from the access point, and providing the auditors with the access point ARN and necessary IAM permissions in their account. This process maintains tight control over your data while enabling secure cross-account access.

Some Amazon S3 operations are only controlled at the bucket level and can’t be controlled by access points. Core bucket operations such as configuring versioning, logging, managing lifecycle policies, and setting up cross-Region replication require direct bucket access. For these operations, you need to interact directly with the bucket through the appropriate permissions. This limitation helps make sure that fundamental bucket configurations remain centralized and controlled by bucket owners.

Creating a dedicated IAM role for bucket administration tasks—separate from the roles that interact with data through access points—enhances security and aligns with the principle of least privilege.

Conclusion

In this second part of a two-part post, you’ve learned about multiple solutions for secure file sharing using AWS services and the pros and cons of each. You can find additional options and a full decision matrix in Part 1. The optimal solution depends on your specific organizational requirements, technical capabilities, and budget constraints. You don’t have to choose just one option, you can implement multiple solutions to address different use cases, creating a file sharing strategy that balances security, cost, and operational efficiency.

Additional resources:

If you have feedback about this post, submit comments in the Comments section below.

Swapnil Singh

Swapnil Singh

Swapnil is a Senior Solutions Architect for AWS World Wide Public Sector. As a Product Acceleration Solutions Architect at AWS, she currently works with GovTech customers to ideate, design, validate, and launch products using cloud-native technologies and modern development practices.

Sumit Bhati

Sumit Bhati

Sumit is a Senior Customer Solutions Manager at AWS, specializing in expediting the cloud journey for enterprise customers. Sumit is dedicated to assisting customers through every phase of their cloud adoption, from accelerating migrations to modernizing workloads and facilitating the integration of innovative practices.

Amazon CloudFront simplifies web application delivery and security with new user-friendly interface

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/amazon-cloudfront-simplifies-web-application-delivery-and-security-with-new-user-friendly-interface/

Today, we’re announcing a new simplified onboarding experience for Amazon CloudFront that developers can use to accelerate and secure their web applications in seconds. This new experience, along with improvements to the AWS WAF console experience, makes it easier than ever for developers to configure content delivery and security services without requiring deep technical expertise.

Setting up content delivery and security for web applications traditionally required navigating multiple Amazon Web Services (AWS) services and making numerous configuration decisions. With this new CloudFront onboarding experience, developers can now create a fully configured distribution with DNS and a TLS certificate in just a few clicks.

Amazon CloudFront offers compelling benefits for organizations of all sizes looking to deliver content and applications globally. As a content delivery network (CDN), CloudFront significantly improves application performance by serving content from edge locations closest to your users, reducing latency and improving user experience. Beyond performance, CloudFront provides built-in security features that protect your applications from distributed denial of service (DDoS) attacks and other threats at the edge, preventing malicious traffic from reaching your origin infrastructure. The service automatically scales with your traffic demands without requiring any manual intervention, handling both planned and unexpected traffic spikes with ease. Whether you’re running a small website or a large-scale application, the CloudFront integration with other AWS services and the new simplified console experience makes it easier than ever to implement these essential capabilities for your web applications.

Streamlined CloudFront configuration

The new CloudFront console experience guides developers through a simplified workflow that starts with the domain name they want to use for their distribution. When using Amazon Route 53, the experience automatically handles TLS certificate provisioning and DNS record configuration, while incorporating security best practices by default. This unified approach eliminates the need to switch between multiple services like AWS Certificate Manager, Route 53, and AWS WAF, and offers developers a faster time to production without the need to dive deep on the nuanced configuration options of each service.

For example, a developer can now create a secure CloudFront distribution for their applications fronted by a load balancer by entering their domain name and selecting their load balancer as the origin. The console automatically recommends optimal CDN and security configurations based on the application type and requirements, and developers can deploy with confidence knowing they’re following AWS best practices.

For developers who wish to host a static website on Amazon Simple Storage Service (Amazon S3), CloudFront provides several important benefits. First, it improves your website’s performance by caching content at edge locations closer to your users, reducing latency and improving page load times. Second, it helps protect your S3 bucket by acting as a security layer—CloudFront can be configured to be the only way to access your content, preventing direct access to your S3 bucket. The new experience automatically configures these security best practices for you.

Enhanced security integration with AWS WAF

Complementing the new CloudFront experience, we’re also introducing an improved AWS WAF console that features intelligent Rule Packs—curated sets of security rules based on application type and security requirements. These Rule Packs enable developers to implement comprehensive security controls without needing to be security experts.

When creating a CloudFront distribution, developers can now enable AWS WAF protection through an integrated experience that uses these new Rule Packs. The console provides clear recommendations for security configurations that developers can use to preview and validate their settings before deployment.

Web applications face numerous security threats today, including SQL injection attacks, cross-site scripting (XSS), and other OWASP Top 10 vulnerabilities. With the new AWS WAF integration, you automatically get protection against these common attack vectors. The recommended Rule Packs provide immediate protection against malicious bot traffic, common web exploits, and known bad actors while preventing direct-to-origin attacks that could overwhelm your infrastructure.

Let’s take a look

If you’ve ever created an Amazon CloudFront distribution, you’ll immediately notice that things have changed. The new experience is straightforward to follow and understand. For my example, I chose to create a distribution for a static website using Amazon S3 as my origin.

New onboarding experience for Amazon CloudFront

In Step 1, I give my distribution a name and select from Single website or app or the new Multi-tenant architecture option, which I can use to configure distributions that use multiple domains but share a common configuration. I choose Single website or app and enter an optional domain name. With the new experience, I can use the Check domain button to verify I have my domain as a Route 53 zone file.

Next, I select the origin for the distribution, which is where CloudFront will fetch the content to serve and cache. For my Origin type, I select Amazon S3. As the preceding screenshot shows, there are several additional options to choose from. Each of the options is designed to make configuration as straightforward as possible for the most popular use cases. Next, I select my S3 bucket, either by typing in the bucket name or using the Browse S3 button.

Next, I have several settings related to using Amazon S3 as my origin. The Grant CloudFront access to origin option is an important one. This option (selected by default) will update my S3 bucket policy to allow CloudFront to access my bucket and will configure my bucket for origin access control. This way, I can use a completely private bucket and know that assets in my bucket can only be accessed through CloudFront. This is a critical step to keeping my bucket and assets secure.

In the next step, I’m presented with the option to configure AWS WAF. With AWS WAF enabled, my web servers are better protected because it inspects each incoming request for potential threats before allowing them to make their way to my web servers. There is a cost to enabling AWS WAF, and as you can see in the following screenshot, there is a calculator to help estimate additional charges.

New onboarding experience for Amazon CloudFront

Now available

The new CloudFront onboarding experience and enhanced AWS WAF console are available today in all AWS Regions where these services are offered. You can start using these new features through the AWS Management Console. There are no additional charges for using these new experiences—you pay only for the CloudFront and AWS WAF resources you use, based on their respective pricing models.

To learn more about the new CloudFront onboarding experience and AWS WAF improvements, visit the Amazon CloudFront Documentation and AWS WAF Documentation. Start building faster, more secure web applications today with these simplified experiences.

AWS Weekly Roundup: Amazon Nova Premier, Amazon Q Developer, Amazon Q CLI, Amazon CloudFront, AWS Outposts, and more (May 5, 2025)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-nova-premier-amazon-q-developer-amazon-q-cli-amazon-cloudfront-aws-outposts-and-more-may-5-2025/

Last week I went to Thailand to attend the AWS Summit Bangkok. It was an energizing and exciting event. We hosted the Developer Lounge, where developers can meet, discuss ideas, enjoy lightning talks, win SWAGs at AWS Builder ID Prize Wheel, take a challenge at Amazon Q Developer Coding Challenge, or learn Generative AI at Learn Amazon Bedrock booth.

Here’s a quick look:

Thank you to AWS Heroes, AWS Community Builders, AWS User Group leaders and developers for your collaboration.

Coming up next in ASEAN is AWS Summit Singapore—make sure you don’t miss it by registering now.

Last Week’s Launches
Here are some launches last week that caught my attention:

  • Amazon Nova Premier Now Generally Available — Amazon Nova Premier, our most capable model for complex tasks and teacher for model distillation, is now generally available in Amazon Bedrock. It excels at complex tasks requiring deep context understanding and multistep planning, while processing text, images, and videos with a 1M token context length. With Nova Premier and Amazon Bedrock Model Distillation, you can create highly capable, cost-effective, and low-latency versions of Nova Pro, Lite, and Micro, for your specific needs.

  • Amazon Q Developer elevates the IDE experience with new agentic coding experience — This new interactive, agentic coding experience for Visual Studio Code allows Q Developer to intelligently take actions on behalf of the developer. Amazon Q Developer introduces an interactive coding experience in Visual Studio Code, offering real-time collaboration for coding, documentation, and testing. It provides transparent reasoning, and supports automated or step-by-step changes in multiple languages.

  • New Foundation Models in Amazon Bedrock — Amazon Bedrock expands its model offerings with two significant additions:
    • Writer’s Palmyra X5 and X4 models feature extensive context windows (1M and 128K tokens respectively) and excel in complex reasoning for enterprise applications. They support multistep tool-calling and adaptive thinking with high reliability standards.
    • Meta’s Llama 4 Scout 17B and Maverick 17B models offer natively multimodal capabilities using mixture-of-experts architecture for enhanced reasoning and image understanding. They support multiple languages and extended context processing, with simplified integration through the Bedrock Converse API.
  • Second-Generation AWS Outposts Racks Released AWS announces the general availability of second-generation Outposts racks with significant enhancements including the latest x86 EC2 instances, simplified networking, and accelerated networking options. These improvements deliver doubled vCPU, memory, and network bandwidth, 40% better performance, and support for ultra-low latency workloads, making them ideal for demanding on-premises deployments.

  • Amazon CloudFront SaaS Manager Launches — Amazon CloudFront SaaS Manager helps SaaS providers and web hosting platforms efficiently manage content delivery across multiple customer domains. The service dramatically reduces operational complexity while providing high-performance content delivery and enterprise-grade security for every customer domain.

  • Amazon Aurora Now Supports PostgreSQL 17 — Amazon Aurora now supports PostgreSQL 17.4, offering community improvements and Aurora-specific enhancements like optimized memory management and faster failovers. The release includes new features for Babelfish, security fixes, and updated extensions, available in all AWS Regions.
  • CloudWatch Introduces Tiered Pricing for Lambda Logs — Amazon CloudWatch launches tiered pricing for AWS Lambda logs and new delivery destinations. Pricing in US East starts at $0.50/GB for CloudWatch and $0.25/GB for S3 and Firehose, both tiering down to $0.05/GB. This update enhances flexibility in log management across all supporting Regions.
  • RDS for MySQL Updates Minor VersionsAmazon RDS for MySQL now supports minor versions 8.0.42 and 8.4.5, delivering security fixes, bug fixes, and performance improvements. Users can upgrade automatically during maintenance windows or use Blue/Green deployments for safer updates.
  • Amazon Bedrock Model Distillation Generally AvailableAmazon Bedrock Model Distillation is now generally available, supporting new models like Amazon Nova and Claude 3.5. It enables smaller models to accurately predict function calling for Agents, delivering up to 500% faster responses and 75% lower costs with minimal accuracy loss for RAG use cases. The service includes automated workflows for data synthesis and student model training.
  • AI Search Flow Builder for Amazon OpenSearch Service Amazon OpenSearch Service now offers an AI search flow builder for OpenSearch 2.19+ domains. This low-code designer enables creation of sophisticated AI-enhanced search flows using AWS and third-party services, supporting use cases like RAG, query rewriting, and semantic encoding.

From Community.AWS
Here’s my personal favorites posts from community.aws:

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS Summit — Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Poland (6 May), Bengaluru (May 7 – 8), Hong Kong (May 8), Seoul (May 14-15), Singapore (May 29), and Sydney (June 4–5).
  • AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity. You can subscribe for event updates now!
  • AWS Partners Events – You’ll find a variety of AWS Partner events that will inspire and educate you, whether you are just getting started on your cloud journey or you are looking to solve new business challenges.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Yerevan, Armenia (May 24), Zurich, Switzerland (May 25), and Bengaluru, India (May 25).

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Reduce your operational overhead today with Amazon CloudFront SaaS Manager

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/reduce-your-operational-overhead-today-with-amazon-cloudfront-saas-manager/

Today, I’m happy to announce the general availability of Amazon CloudFront SaaS Manager, a new feature that helps software-as-a-service (SaaS) providers, web development platform providers, and companies with multiple brands and websites efficiently manage delivery across multiple domains. Customers already use CloudFront to securely deliver content with low latency and high transfer speeds. CloudFront SaaS Manager addresses a critical challenge these organizations face: managing tenant websites at scale, each requiring TLS certificates, distributed denial-of-service (DDoS) protection, and performance monitoring.

With CloudFront Saas Manager, web development platform providers and enterprise SaaS providers who manage a large number of domains will use simple APIs and reusable configurations that use CloudFront edge locations worldwide, AWS WAF, and AWS Certificate Manager. CloudFront SaaS Manager can dramatically reduce operational complexity while providing high-performance content delivery and enterprise-grade security for every customer domain.

How it works
In CloudFront, you can use multi-tenant SaaS deployments, a strategy where a single CloudFront distribution serves content for multiple distinct tenants (users or organizations). CloudFront SaaS Manager uses a new template-based distribution model called a multi-tenant distribution to serve content across multiple domains while sharing configuration and infrastructure. However, if supporting single websites or application, a standard distribution would be better or recommended.

A template distribution defines the base configuration that will be used across domains such as origin configurations, cache behaviors, and security settings. Each template distribution has a distribution tenant to represent domain-specific origin paths or origin domain names including web access control list (ACL) overrides and custom TLS certificates.

Optionally, multiple distribution tenants can use the same connection group that provides the CloudFront routing endpoint that serves content to viewers. DNS records point to the CloudFront endpoint of the connection group using a Canonical Name Record (CNAME).

To learn more, visit Understand how multi-tenant distributions work in the Amazon CloudFront Developer Guide.

CloudFront SaaS Manager in action
I’d like to give you an example to help you understand the capabilities of CloudFront SaaS Manager. You have a company called MyStore, a popular e-commerce platform that helps your customer easily set up and manage an online store. MyStore’s tenants already enjoy outstanding customer service, security, reliability, and ease-of-use with little setup required to get a store up and running, resulting in 99.95 percent uptime for the last 12 months.

Customers of MyStore are unevenly distributed across three different pricing tiers: Bronze, Silver, and Gold, and each customer is assigned a persistent mystore.app subdomain. You can apply these tiers to different customer segments, customized settings, and operational Regions. For example, you can add AWS WAF service in the Gold tier as an advanced feature. In this example, MyStore has decided not to maintain their own web servers to handle TLS connections and security for a growing number of applications hosted on their platform. They are evaluating CloudFront to see if that will help them reduce operational overhead.

Let’s find how as MyStore you configure your customer’s websites distributed in multiple tiers with the CloudFront SaaS Manager. To get started, you can create a multi-tenant distribution that acts as a template corresponding to each of the three pricing tiers the MyStore offers: Bronze, Sliver, and Gold shown in Multi-tenant distribution under the SaaS menu on the Amazon CloudFront console.

To create a multi-tenant distribution, choose Create distribution and select Multi-tenant architecture if you have multiple websites or applications that will share the same configuration. Follow the steps to provide basic details such as a name for your distribution, tags, and wildcard certificate, specify origin type and location for your content such as a website or app, and enable security protections with AWS WAF web ACL feature.

When the multi-tenant distribution is created successfully, you can create a distribution tenant by choosing Create tenant in the Distribution tenants menu in the left navigation pane. You can create a distribution tenant to add your active customer to be associated with the Bronze tier.

Each tenant can be associated with up to one multi-tenant distribution. You can add one or more domains of your customers to a distribution tenant and assign custom parameter values such as origin domains and origin paths. A distribution tenant can inherit the TLS certificate and security configuration of its associated multi-tenant distribution. You can also attach a new certificate specifically for the tenant, or you can override the tenant security configuration.

When the distribution tenant is created successfully, you can finalize this step by updating a DNS record to route traffic to the domain in this distribution tenant and creating a CNAME pointed to the CloudFront application endpoint. To learn more, visit Create a distribution in the Amazon CloudFront Developer Guide.

Now you can see all customers in each distribution tenant to associate multi-tenant distributions.

By increasing customers’ business needs, you can upgrade your customers from Bronze to Silver tiers by moving those distribution tenants to a proper multi-tenant distribution.

During the monthly maintenance process, we identify domains associated with inactive customer accounts that can be safely decommissioned. If you’ve decided to deprecate the Bronze tier and migrate all customers who are currently in the Bronze tier to the Silver tier, then you can delete a multi-tenant distribution to associate the Bronze tier. To learn more, visit Update a distribution or Distribution tenant customizations in the Amazon CloudFront Developer Guide.

By default, your AWS account has one connection group that handles all your CloudFront traffic. You can enable Connection group in the Settings menu in the left navigation pane to create additional connection groups, giving you more control over traffic management and tenant isolation.

To learn more, visit Create custom connection group in the Amazon CloudFront Developer Guide.

Now available
Amazon CloudFront SaaS Manager is available today. To learn about, visit CloudFront SaaS Manager product page and documentation page. To learn about SaaS on AWS, visit AWS SaaS Factory.

Give CloudFront SaaS Manager a try in the CloudFront console today and send feedback to AWS re:Post for Amazon CloudFront or through your usual AWS Support contacts.

Veliswa.
_______________________________________________

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

AWS Weekly Roundup: Upcoming AWS Summits, Amazon Q Developer, Amazon CloudFront updates, and more (April 21, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-upcoming-aws-summits-amazon-q-developer-amazon-cloudfront-updates-and-more-april-21-2025/

Last week, we had the AWS Summit Amsterdam, one of the global Amazon Web Services (AWS) events that offers you the opportunity to learn from technical and industry leaders, and meet AWS experts and like-minded professionals. In particular, most AWS Summits have Developer and Community Lounges in their exhibition halls.

AWS Summit Amsterdam - DevLoungeA photo taken by Thembile Martis in AWS Summit Amsterdam 2025
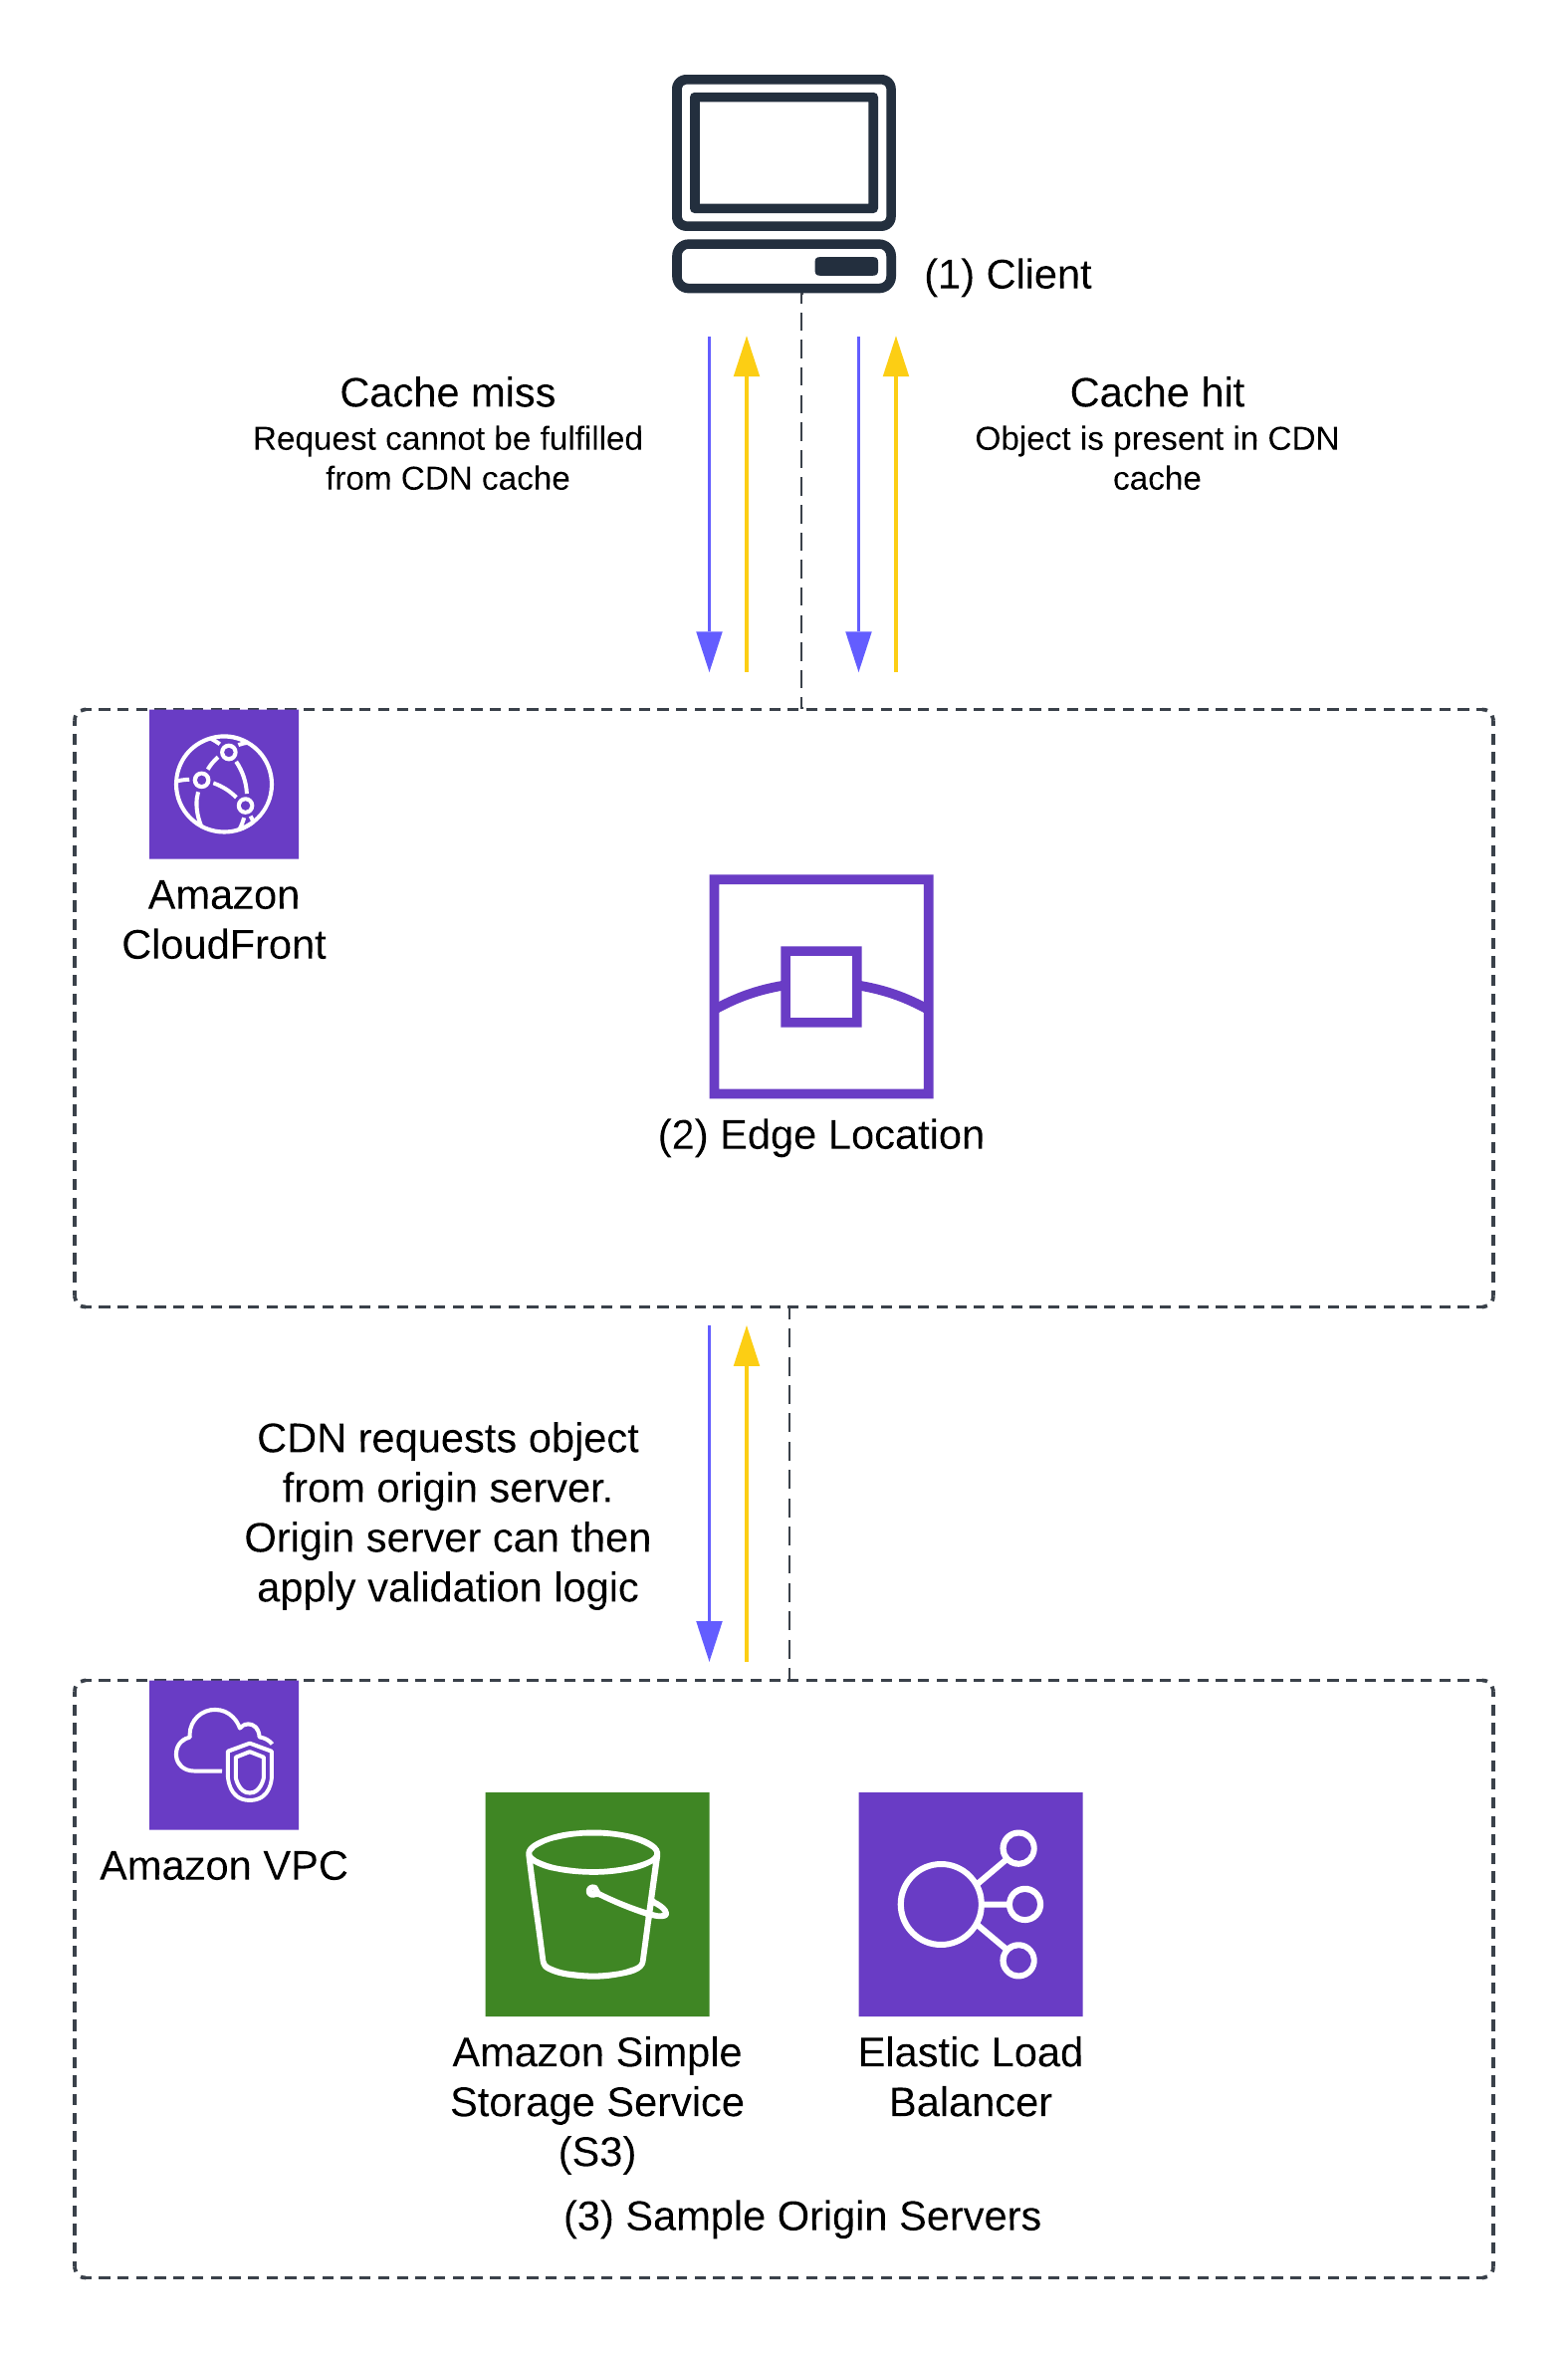
Here, you can experience generative AI services for developers or participate in developer sessions prepared by the AWS community. You can also take a turn at the prize wheel, where you can receive special gifts after signing up for AWS Builder ID to use Amazon Q Developer, AWS Skill Builder, AWS re:Post, and AWS Community for developers.

Check your schedule and join an AWS Summit in a city near you: Bangkok (April 29), London (April 30), Poland (May 5), Bengaluru (May 7–8), Hong Kong (May 8), Seoul (May 14–15), Dubai (May 21), Tel Aviv (May 28), Singapore (May 29), Stockholm (June 4), Sydney (June 4-5), Hamburg (June 5), Washington, D.C, (June 10–11), Madrid (June 11), Milan (June 18), Shanghai (June 19–20), Mumbai (June 19), and Tokyo (June 25–26).

Last week’s launches
Here are some launches that got my attention:

  • GitLab Duo with Amazon Q – GitLab Duo with Amazon Q is generally available for Self-Managed Ultimate customers, embedding advanced agent capabilities for software development. It also supports Java modernization, enhanced quality assurance, and code review optimization directly in GitLab’s enterprise DevSecOps platform. To learn more, read the DevOps blog post or visit the Amazon Q Developer integrations page to learn more.
  • Amazon Q Developer in the Europe (Frankfurt) Region – Amazon Q Developer Pro tier customers can now use and configure Amazon Q Developer in the AWS Management Console and in the integrated development environment (IDE) to store data in the Europe (Frankfurt) Region. It performs inference in European Union (EU) Regions giving them more choice over where their data resides and transits. To learn more, read the blog post.
  • New 223 AWS Config rules in AWS Control Tower – AWS Control Tower supports an additional 223 managed Config rules in Control Catalog for various use cases such as security, cost, durability, and operations. With this launch, you can now search, discover, enable and manage these additional rules directly from AWS Control Tower and govern more use cases for your multi-account environment. To learn more, visit the AWS Control Tower User Guide.
  • Amazon CloudFront Anycast Static IPs support for apex domains – You can easily use your root domain (for example, example.com) with CloudFront. This new feature simplifies DNS management by providing only three static IP addresses instead of the previous 21, making it easier to configure and manage apex domains with CloudFront distributions. To learn more, visit the CloudFront Developer Guide for detailed documentation and implementation guidance.
  • AWS Lambda@Edge advanced logging controls – This feature improves how Lamgda function logs are captured, processed, and consumed at the edge. This enhancement provides you with more control over your logging data, making it easier to monitor application behavior and quickly resolve issues. To learn more, read the Compute blog post, the Lambda Developer Guide, or the CloudFront Developer Guide.
  • New AWS Wavelength Zone in Dakar, Senegal – With this first Wavelength Zone in sub-Saharan Africa in a partnership with Sonatel, an affiliate of Orange, independent software vendors (ISVs), enterprises, and developers can now use AWS infrastructure and services to support applications with data residency, low latency, and resiliency requirements. AWS Wavelength is available in 31 cities across the globe in a partnership with seven telecommunication companies. To learn more, visit AWS Wavelength and get started today.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Here are some additional news items that you might find interesting:

From community.aws
Here are my personal favorites posts from community.aws:

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity. You can subscribe for event updates now!
  • AWS Partners Events – You’ll find a variety of AWS Partner events that will inspire and educate you, whether you are just getting started on your cloud journey or you are looking to solve new business challenges.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Istanbul, Turkey (April 25), Prague, Czech Republic (April 25), Yerevan, Armenia (May 24), Zurich, Switzerland (May 25), and Bengaluru, India (May 25).

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Channy

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

How to help prevent hotlinking using referer checking, AWS WAF, and Amazon CloudFront

Post Syndicated from Alex Smith original https://aws.amazon.com/blogs/security/how-to-prevent-hotlinking-by-using-aws-waf-amazon-cloudfront-and-referer-checking/

Note: This post was first published April 21, 2016. The updated version aligns with the latest version of AWS WAF (AWS WAF v2) and includes screenshots that reflect the changes in the AWS console experience.


AWS WAF Classic has been deprecated and will be end-of-life (EOL) in September 2025. This update describes how to use the latest version of AWS WAF (WAFv2) to help prevent hotlinking. Updates have been made to the screenshots to reflect the changes in the AWS Management Console for AWS WAF.

Hotlinking—also known as inline linking—is a form of content leeching where an unauthorized third-party website embeds links to resources originally referenced in a primary site’s HTML. The third-party website doesn’t incur the cost of hosting the content, which means that your website can be charged for the content other sites use. It also results in slow loading times, lost revenue, and potential legal issues.

Now, you can use AWS WAF to help prevent hotlinking. AWS WAF is a web application firewall that’s closely integrated with Amazon CloudFront—a content delivery network (CDN)—and can help protect your web applications from common web exploits that could affect application availability, compromise security, and consume excessive resources. In this blog post, I show you how to help prevent hotlinking by using header inspection in AWS WAF, while still taking advantage of the improved user experience from a CDN such as CloudFront.

Solution overview

You can address hotlinking in various ways. For instance, you can validate the Referer header (sent by a browser to indicate to the server which page the visitor was referred from) at your web server (for example, by using the Apache module mod_rewrite), and either issue a redirect back to your site’s main page or return a 403 Forbidden error to the visitor’s browser.

If you’re using a CDN such as CloudFront to speed up your site’s delivery of content, validating the Referer header at the web server becomes less practical. The CDN stores a copy of your content in the edge of its network of servers, so even if your web server validates the original request’s headers (in this case, the referer), additional requests for that content must be validated by the CDN itself, because they are unlikely to reach the origin web server.

Figure 1 illustrates this process.

Figure 1: Request – response flow showing instances of a cache-miss and a cache-hit

Figure 1: Request – response flow showing instances of a cache-miss and a cache-hit

The process shown in Figure 1 is as follows:

  1. A request is received from a user client (1) at a CloudFront edge location (2).
  2. The edge location attempts to return a cached copy of the file requested. This request, if fulfilled from the cache, is considered a cache hit.
    1. In the case of a cache miss—when the content is either not in the edge or is not valid (for example, if the content is out of date)—the request is forwarded to the origin (3) (such as an Amazon Simple Storage Service (Amazon S3) bucket) for a new copy of the object.
    2. In the case of a cache hit, the origin cannot apply validation logic to the user’s request, because the edge server doesn’t need to contact the origin to fulfil the user’s request.

In the next section, I show you how to inspect the client-request headers using AWS WAF to allow or block requests at the CDN.

Solution implementation—two approaches

This post includes two ways to set up AWS WAF to help prevent hotlinking:

  • Using a separate subdomain: Static files (such as images or styling components) to be protected are moved to a separate subdomain such as static.example.com so that you only need to validate the Referer header.
  • Using the same domain: Static files are located under a directory on the same domain. This solution includes how to extend this example to check for an empty Referer header.

The choice of approach will depend on how your site is structured and the level of protection you want to implement. The first approach enables you to set up a Referer header check to make sure that requests for the images only come from an allowlisted sub-domain, while the second approach has an additional check for an empty Referer header. The second approach extends the first approach and allows for some flexibility for users to share direct links to the image while still preventing unaffiliated third-party sites from embedding the image links on their websites.

Terms

The following list includes key terms used in this post:

  • AWS WAF configurations consist of a web access control list (web ACL), associated with a given CloudFront distribution.
  • Each web ACL is a collection of one or more rules, and each rule can have one or more match conditions.
  • Match conditions are made up of one or more filters, which inspect components of the request (such as its headers or URI) to match for certain conditions.
  • Case-sensitivity: HTTP header names are case-insensitive. Referer and referer point to the same HTTP header. HTTP header values, however, are case-sensitive.

Prerequisites

You must have a CloudFront distribution set up before configuring an AWS WAF web ACL. For information about how to set up a CloudFront distribution with an S3 bucket as an origin, see Configure distributions.

Approach 1: A separate subdomain

In this example, you create an AWS WAF rule set that contains a single rule with a single match condition, which in turn has a single filter. The match condition checks the Referer header and verifies that it contains a given value. If the request matches the condition specified in the rule, the traffic is allowed. Otherwise, the AWS WAF rule blocks the traffic.

For this example, because all the static files are on a separate subdomain (static.example.com) accessed only from the site example.com, you will block hotlinking for any file that don’t have a referer that ends with example.com.

Use the following steps to set this up using the AWS WAF console.

Step 1: Create and name a new web ACL

  1. Sign in to the AWS WAF console.
  2. If you have not created a web ACL before, Choose Create web ACL on the AWS WAF console landing page.
  3. Because you want to associate the web ACL with a CloudFront distribution, select Amazon CloudFront distributions as the Resource type.
    1. Enter a Name for the web ACL that you’re creating. For this example, I used the name sample-webacl. The page will automatically populate an associated Amazon CloudWatch metric name. CloudWatch is a monitoring service that allows you to gather and report on metrics of various services. This CloudWatch metric can be used later to report on how your newly created AWS WAF configuration is being used.
    2. After you have supplied the name of the web ACL, you can select the available AWS resources to be protected by this web ACL. In this example, you will fill that in later, so leave this field blank for now.
    3. By default, AWS WAF can inspect up to 16 KB of the web request body with additional values of 32, 48, and 64 KB for an additional cost. Leave the web request Body size limit at the default value of 16 KB.
    4. Choose Next.
  4. Figure 2: Describing the web ACL and associating it to resources

    Figure 2: Describing the web ACL and associating it to resources

Step 2: Create a string match condition on Referer header

AWS WAF ACLs can use AWS managed rule groups, rule groups from AWS Marketplace providers, or you can write your own rules and rule groups. For this example, you will create your own rules and rule groups.

  1. In the AWS WAF console, choose Add rules, and select Add my own rules and rule groups to create the string match condition.
    Figure 3: Add rules and rule groups

    Figure 3: Add rules and rule groups

  2. This will bring you to the Rule visual editor page. The default Rule type will be set to Rule builder which you can leave unchanged. In the Rule builder section, select Regular rule.
    Figure 4: Rule type and Rule builder

    Figure 4: Rule type and Rule builder

  3. The next step is to construct a string match condition to match on the Referer header. Under Name, enter a name for the rule, such as Referer-check. Make sure that If a request is set to doesn’t match the statement (NOT). The string match condition is a negative match which means that if the Referer header field value does not match the value specified in the rule, the request will be blocked. This makes sure that requests for static.example.com which only originate from example.com are allowed. In the Statement section, use the following settings:
    1. Inspect: Select Single header.
    2. Header field name: Enter referer as the value.
    3. Match type: Select Exactly matches string.
    4. String to match: Enter example.com as the value.
    5. Text transformation: Select Lowercase. This isn’t required for most modern browsers, but is a good practice because HTTP header field values are case sensitive.
    Figure 5: Rule name and statement

    Figure 5: Rule name and statement

  4. In the Action section, select Block as the Action. Choose Add Rule.
    Figure 6: Rule Action

    Figure 6: Rule Action

    In the preceding rule statement, you’re configuring AWS WAF to inspect a header with the name Referer and checking if the value of the header matches the static string example.com. If the value of the Referer header is not example.com, then the request is blocked.

  5. The next page is Add rules and rule groups. It shows the following attributes of the web ACL:
    1. AWS WAF rules that have been added to the web ACL.
    2. Web ACL capacity units (WCUs).
    3. Default web ACL action.
    4. Token domain list.
    5. Because you’re only adding one rule to this web ACL, choose Next.
      Figure 7: Rules and rule groups, WCUs, and default web ACL action

      Figure 7: Rules and rule groups, WCUs, and default web ACL action

  6. On the next page, you will set the rule priority. Because you added only one rule, you will not need to adjust the rule priority. If there is more than one rule, you can select a particular rule and use the Move up or Move down options to organize the rule order. Choose Next.
    Figure 8: Set rule priority

    Figure 8: Set rule priority

  7. The Configure metrics page details can be left at the default values. Choose Next to proceed to the final step.
    Figure 9: Configure metrics

    Figure 9: Configure metrics

  8. The final step is to review the web ACL details. If you need to change one of the settings of the web ACL, you can choose Edit step for the corresponding step. Choose Create web ACL to finalize creating the AWS WAF web ACL.
    Figure 10: Review and create web ACL

    Figure 10: Review and create web ACL

Step 3: Associate the new rule with the relevant CloudFront distribution

You can now associate AWS resources with the web ACL that you created in the previous steps. In this case, the AWS resource is a CloudFront distribution.

  1. In the AWS WAF console, choose Web ACLs in the navigation pane. Select the web ACL named sample-webacl that you created previously.
    Figure 11: Select a Web ACL to configure

    Figure 11: Select a Web ACL to configure

  2. Choose Add AWS resources.
    Figure 12: Add AWS resources

    Figure 12: Add AWS resources

  3. Eligible AWS resources will be displayed in the pop-up page. Select the CloudFront distribution from the Resources list. Choose Add to associate the ACL sample-webacl with the CloudFront distribution.
    Figure 13: Select CloudFront distribution to associate with sample-webacl

    Figure 13: Select CloudFront distribution to associate with sample-webacl

  4. The next page is the Web ACLs page, which will show the CloudFront distribution selected in the previous step in the Associated AWS resources section.
    Figure 14: Web ACLs and Associated AWS resources

    Figure 14: Web ACLs and Associated AWS resources

Test the referer check rule

You’re ready to test the web ACL that you created by issuing a cURL command from the command line and confirming that the referer check is matched correctly. When you request files without the allowlisted Referer header, the requests are blocked at the CDN. However, valid requests still are allowed through.

When a third party embeds your content (request blocked at the CDN)

» curl –H "Referer: example.net -I https://static.example.com/favicon.ico
« HTTP/1.1 403 Forbidden

When you embed your content (request allowed through the CDN)

» curl –H "Referer: example.com -I https://static.example.com/favicon.ico
« HTTP/1.1 200 OK

Note: With Approach 1, you must make the request with an allowlisted Referer header. In this example, all paths are filtered.

Approach 2: All content under the same domain, with filtering by path

In the second approach, you allow a blank Referer header and filter by a given URL path. To do this, you will create an AWS WAF web ACL that contains multiple rules with additional match conditions, which in turn are comprised of multiple filters. As with the first approach, the match condition looks at the Referer header; however, you will validate the header in two ways. First, you validate whether the request contains the expected header, and if it does not, you apply the second validation, which checks to see whether it has a URL style Referer header. This enables you to access the assets directly in a browser when the assets aren’t embedded elsewhere in a website but still provides protection against hotlinking.

Accessing an image directly in the browser can be useful in situations where users might want to share the link to the image directly, thus helping to prevent a negative user experience when sharing the image link with other users. This approach makes it an improvement over the first approach where requests for the images must originate from the sub-domain.

You will also validate the path used in the request (in this example /wp-content), which allows AWS WAF to protect individual folders under a single domain name.

Step 1: Decide what to protect

As in the first approach, rather than filter on everything under a domain, you will filter based on the path. In this case, /wp-content. This allows you to protect your uploaded content that sits under /wp-content, but without having to put the content into a separate subdomain.

Step 2: Create and name a new web ACL

You can use the web ACL that you created for Approach 1, or you can repeat Step 1 of Approach 1 to create a new web ACL.

Step 3: Create string match conditions on the referer

For Approach 2, the assumption is that everything exists under a single domain, so instead of using the catch-all example.com, use the more secure https://example.com/ and mark the header as Starting with https://example.com.

Because you’re explicitly filtering on one header, you must watch out for two things:

  • Switching between www.example.com and example.com in your application.
  • Switching between https:// and http:// in your application.

If either of these switches occurs, you will see a 403 Forbidden error returned instead of your embedded files. In this example, all content is delivered directly through https://example.com/.

For this example, you will construct two rules, each of which will contain multiple string match conditions. AWS WAF allows for conditional match conditions within a rule so you can create nested logic statements. For example, a rule evaluation is true if all the statements within a rule statement are evaluated to true.

First rule: Validate a Referer header:

For this rule, you will set the following match conditions and AWS WAF actions:

Rule name: Validate-Referer-header

If Referer header value starts with https://example.com

AND

If URI path starts with /wp-content

THEN

ALLOW request

  1. Open the AWS Management Console for AWS WAF and navigate to WAF & Shield.
  2. Choose Web ACLs in the navigation pane and select Global (CloudFront) as the AWS Region.
    Figure 15: Web ACLs and AWS Regions

    Figure 15: Web ACLs and AWS Regions

  3. The page will refresh to show the Web ACL sample-webacl that you created in the preceding Step 2. Select sample-webacl.
    Figure 16: Web ACLs list

    Figure 16: Web ACLs list

  4. Select the Rules tab.
    Figure 17: Web ACL rules

    Figure 17: Web ACL rules

  5. Choose Add rules and select Add my own rules and rule groups. If you’re reusing the web ACL created in Approach 1, delete the Referer-check rule before adding new rules.
    Figure 18: Add rules and rule groups

    Figure 18: Add rules and rule groups

  6. For Rule type, select Rule builder.
    Figure 19: Rule type

    Figure 19: Rule type

  7. In the Rule section, use the following settings:
    1. Name: Enter Validate-referer-header as the value.
    2. Type: Select Regular rule.
    3. If a request: Select matches all the statements (AND).
    Figure 20: Rule name and match condition

    Figure 20: Rule name and match condition

  8. In the Statement 1 section, use the following settings:
    1. Inspect: Select Single header.
    2. Header field name: Enter referer as the value.
    3. Match type: Select Starts with string.
    4. String to match: Enter https://example.com as the value.
    5. Text transformation: Select Lowercase.
    Figure 21: First string match condition

    Figure 21: First string match condition

  9. Create the second string match condition (Statement 2). For the URL itself, you want to protect content under /wp-content, so you will create a string match to validate that case using the same steps as for the first string match condition, with two changes:
    1. For Inspect, select URI path.
    2. For String to match, enter /wp-content as the value.
    Figure 22: Second string match condition

    Figure 22: Second string match condition

  10. Change the Action to Allow and choose Add Rule at the bottom of the page.
    Figure 23: Set the Action to Allow

    Figure 23: Set the Action to Allow

  11. In the Set rule priority page, choose Save.
    Figure 24: Save the rule

    Figure 24: Save the rule

Second rule: Validate without a Referer header

For the second rule, you will set the following match conditions and rule actions:

Rule name: Validate- with-no-Referer-header

If Referer header contains ://

AND

If URI path starts with /wp-content

THEN

BLOCK request

The second rule is similar to the first rule, but it matches when the Referer header value includes ://. You use this match condition to check whether the Referer header has been set at all. If it has, you block the request.

  1. In the Web ACL page, choose Add rules and select Add my own rules and rule groups to be taken to the Rule type page.
    Figure 25: Create the second rule

    Figure 25: Create the second rule

  2. For Rule type and Rule builder, use the following settings:
    1. Rule type: Select Rule builder.
    2. Name: Enter Validate-with-no_Referer-header as the value.
    3. Type: Select Regular rule.
    4. If a request: Select matches all the statements (AND).
    Figure 26: Set the rule type and matching

    Figure 26: Set the rule type and matching

  3. For Statement 1, use the following settings:
    1. Inspect: Select Single header.
    2. Header field name: Enter Referer as the value.
    3. Match type: Select Contains string.
    4. String to match: Enter ://
    Figure 27: Configure Statement 1

    Figure 27: Configure Statement 1

  4. For Statement 2, use the following settings:
    1. Inspect: Select URI path.
    2. Match type: Select Starts with string.
    3. String to match: Enter /wp-content as the value.
    Figure 28: Configure Statement 2

    Figure 28: Configure Statement 2

  5. For Action, keep the default setting of Block and choose Add Rule.
    Figure 29: Add rule

    Figure 29: Add rule

  6. The resulting Set rule priority page will list the rules in the sample-webacl web ACL and will look like the following figure. It shows the name of the rule, the rule priority, the web capacity units (WCUs) and the AWS WAF response. Choose Save.
    Figure 30: Rule priority and web ACL units used the web ACL.

    Figure 30: Rule priority and web ACL units used the web ACL.

The Rules tab will now show both of the rules that you added with their corresponding AWS WAF actions in addition to the default action of Allow for requests that don’t match one of the rules.

Figure 31: Rules tab of sample-webacl web ACL

Figure 31: Rules tab of sample-webacl web ACL

Step 4: Associate the new rules with the relevant CloudFront distribution

  1. Select the Associated AWS Resources tab and choose Add AWS resources.
    Figure 32: Add AWS resources

    Figure 32: Add AWS resources

  2. Select the relevant CloudFront distribution and choose Add.
    Figure 33: Select the CloudFront distribution

    Figure 33: Select the CloudFront distribution

  3. The web ACLs page will show the CloudFront distribution in the Associated AWS resources tab.
    Figure 34: Associated AWS resources

    Figure 34: Associated AWS resources

Test the rules

Similar to Approach 1, you have filtering at the CDN, but this time the filtering is based on the path and direct linking is allowed (without a Referer header).

You can use cURL to verify that the new AWS WAF web ACL correctly protects your content. Use the –H argument to send a different Referer header to the CloudFront distribution, which allows you to test as if you are embedding the website content in an unauthorized page.

When a third party embeds your content

» curl –H "Referer: https://example.net/" -I https://example.com/wp-content/uploads/2013/03/shareable-image.jpg
« HTTP/1.1 403 Forbidden

When your content is directly linked (with no Referer)

» curl -I https://example.com/wp-content/uploads/2013/03/shareable-image.jpg
« HTTP/1.1 200 OK

When you embed your content

» curl –H "Referer: https://example.com/" -I https://example.com/wp-content/uploads/2013/03/shareable-image.jpg
« HTTP/1.1 200 OK

Conclusion

AWS WAF is a web application firewall that lets you monitor and control the HTTP(S) requests that are forwarded to your protected web application resources. In this post, you saw how to use the AWS WAF custom rule builder feature to prevent content hotlinking to protect your website’s content hosted in an Amazon S3 bucket.

The two approaches demonstrated in this post provide you with ways to implement a robust referer check solution that helps prevent unauthorized third-party websites from linking back to static assets on your website, thus helping to prevent increased bandwidth costs, bad user experience, and degraded performance because of resource leeching. Following the concept of least privilege, you can further restrict the AWS WAF rules to apply only to certain image file extensions (such as .jpg or .png).

While referer checking helps prevent unaffiliated sites from backlinking to your site’s images and benefitting by using your site’s bandwidth, more sophisticated exploits can carefully craft a request to bypass the referer check. Other web request mechanisms, such as web browser plugins, server-to-server requests that forge referer header values, or privacy-based web browsers may also cause inconsistencies in accurately evaluating the referer header value. Be aware of such inconsistencies and consider using additional private content mechanisms such as signed URLs and token authentication.

Web browsers don’t have a mechanism to validate if a Referer header has been tampered with. Referer checking should be implemented as part of a broader web application security strategy by using AWS WAF application protection rules, Bot Control, Fraud Control, and Distributed Denial of Service (DDOS) protection. Effective web traffic monitoring using AWS WAF logs, Amazon CloudWatch metrics, and web ACL traffic dashboards will help ensure that bad actors aren’t bypassing the AWS WAF rules that you have set up to protect your web traffic.

You can use AWS WAF to build on top of the referer check to implement more advanced content protection solutions such as rate-limiting, bot mitigation, and DDOS mitigations to further secure your website against a wide range of exploits.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this solution or its implementation, start a new thread on the AWS WAF forum.

Alex Smith was the original author of this post in 2016.

Sanchith Kandaka

Sanchith Kandaka

With over 15 years of experience in the Content Delivery and Application Security space, Sanchith is excited about all things edge related. He has worked as a Solutions Architect and a Solutions Engineer and is now a Specialist Solutions Architect at AWS focused on AWS Edge Services and Perimeter Protection services including Amazon CloudFront, AWS WAF, and AWS Shield.

How UNiDAYS achieved AWS Region expansion in 3 weeks

Post Syndicated from Sanhawat Taongern original https://aws.amazon.com/blogs/architecture/how-unidays-achieved-aws-region-expansion-in-3-weeks/

UNiDAYS is a fast, free digital platform that provides exclusive student offers and benefits to over 29 million verified members worldwide. With a rapidly growing user base and an increasing number of global partnerships, UNiDAYS recognized the need to enhance its platform’s performance to deliver a seamless consumer experience in geographic regions far from its original base of operations.

In this post, we share how UNiDAYS achieved AWS Region expansion in just 3 weeks using AWS services.

Business challenges

In response to growth opportunities, UNiDAYS faced a pressing business requirement: deliver low-latency responses and provide high availability for users across diverse geographic regions. At the same time, the platform needed to guarantee global data consistency while adhering to tight deadlines—all within just a few weeks. However, the existing monolithic application, although built on Amazon Web Services (AWS), wasn’t optimized for active-active multi-Region deployments.

The challenge was further complicated by the need to extend functionality from this legacy system, which used the AWS global network for improved user experience but fell short of meeting new business requirements. Re-architecting the entire platform to support multi-Region deployments within the given timeframe wasn’t feasible.

Solution overview

UNiDAYS opted to create complementary services tailored to these new requirements, using AWS services for a multi-Region, active-active architecture. The key services used included:

This approach allowed UNiDAYS to meet its latency, availability, and consistency goals while seamlessly integrating with existing infrastructure. The following diagram is the architecture for the solution.

Global delivery and resiliency

To provide the lowest latency and multi-Region resiliency, CloudFront was used with latency-based routing configured in Route 53. This routing directs requests to the Regional Application Load Balancers with the lowest latency, automatically providing resiliency in the event of Regional issues. Security was a key consideration. AWS WAF integration with CloudFront provided application-layer protection at the edge. Additional security measures included:

  • Custom HTTP headers on origin requests, enforced using Application Load Balancer listener rule conditions
  • Prefix lists to restrict access to Application Load Balancers, making sure that traffic originated from the intended CloudFront distributions

Rapid Regional deployment

The core infrastructure is deployed through Terraform, and applications are deployed using custom tooling that wraps AWS CloudFormation. This hybrid approach enabled rapid delivery by using existing patterns without disrupting established workflows. Resources were organized into tiers: platform, global, and Regional. Platform and global resources were deployed one time, and Regional resources were rolled out to each activated Region, streamlining expansion efforts.

One technical challenge involved CloudFormation exports, which are Regional by design. To address this, we implemented a custom CloudFormation macro to enable cross-Region access to exported values, providing consistency across deployments.

Amazon ECS enabled progressive application deployments within each Region, allowing teams to focus on scaling applications rather than managing infrastructure. For cost-efficiency, we used Spot Instances. During testing, container start-up latency was observed due to cross-Region image downloads from Amazon Elastic Container Registry (Amazon ECR). This issue was resolved by enabling private image replication in Amazon ECR so that container images were available locally in each Region. This solution significantly reduced start-up times, improving application responsiveness during deployments and scaling events.

Data consistency and performance

DynamoDB global tables were instrumental in providing eventual data consistency and Regional replication. With DynamoDB handling these aspects, we could focus on application logic.

The result was a substantial reduction in latency at key locations. For example, client-experienced latency in one Region dropped from approximately 200 milliseconds to 50 milliseconds upon deployment, as shown in the following screenshot.

Outcome

Key technical hurdles

We addressed the following technical obstacles while developing the solution:

  • Cross-Region CloudFormation exports – CloudFormation exports are Regional by design. We addressed this by creating a custom CloudFormation macro to read exports across Regions.
  • Container start-up latency – Latency caused by cross-Region image downloads was mitigated by implementing Amazon ECR private image replication. This meant that container images were readily available in each Region, reducing deployment times and improving overall performance.
  • Security assurance – By using CloudFront, AWS WAF, and Application Load Balancer security features, we made sure that traffic and data remained secure.

Why AWS?

UNiDAYS chose AWS due to its comprehensive global infrastructure and robust service offerings, which allowed the platform to:

  • Seamlessly expand compute operations to Regions closer to its user base
  • Take advantage of a full stack of services for reliable, secure, and low-latency content delivery
  • Meet tight delivery deadlines without compromising on performance or security
  • Maintain flexibility where required, with the ability to use more managed services, which allowed a focus on our applications

Conclusion

By adopting a multi-Region, active-active architecture on AWS, UNiDAYS successfully met its business goals within only 3 weeks, rapidly expanding to new Regions while promoting platform resiliency. The solution improved latency by 75% in new Regions (from 200 milliseconds to 50 milliseconds), provided Regional data availability through DynamoDB global tables, and maintained 100% service uptime during resiliency tests, even in cases of Regional connectivity loss. Additionally, deployment velocity increased by over 40%, allowing faster feature releases and improved agility. This architecture not only provides a scalable and resilient platform for current operations but also establishes a strong foundation for future global expansion.

Learn more

Is your organization looking to expand into new Regions while maintaining performance and reliability?

  • Contact AWS experts to explore tailored solutions for your multi-Region strategy.
  • Use AWS Global Infrastructure to optimize your expansion.
  • Share your challenges and successes in the comments—we’d love to hear your insights!


About the Authors

Top Architecture Blog Posts of 2024

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

(By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

Without further ado, here are our top posts from 2024!

#10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

Architecture for deploying stable diffusion on ComfyUI

Figure 1. Architecture for deploying stable diffusion on ComfyUI

#9 Let’s Architect! Designing Well-Architected systems

In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

Let's Architect

Figure 2. Let’s Architect

#8 Let’s Architect! Learn About Machine Learning on AWS

As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

Let's Architect

Figure 3. Let’s Architect

If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

#7 Creating an organizational multi-Region failover strategy

Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

#6 Building a three-tier architecture on a budget

Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

Example of a three-tier architecture on AWS

Figure 5. Example of a three-tier architecture on AWS

#5 Announcing updates to the AWS Well-Architected Framework guidance

As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

Well-Architected logo

Figure 6. Well-Architected logo

#4 Let’s Architect! Serverless developer experience in AWS

One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

Let's Architect

Figure 7. Let’s Architect

#3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

Chaos engineering pattern for hybrid architecture (3-tier application)

Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

#2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

Well-Architected logo

Figure 9. Well-Architected logo

#1 How an insurance company implements disaster recovery of 3-tier applications

And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Thank you!

As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

For other top post lists, see our Top 10 and Top 5 posts from previous years.

Node.js 22 runtime now available in AWS Lambda

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/node-js-22-runtime-now-available-in-aws-lambda/

This post is written by Julian Wood, Principal Developer Advocate, and Andrea Amorosi, Senior SA Engineer.

You can now develop AWS Lambda functions using the Node.js 22 runtime, which is in active LTS status and ready for production use. Node.js 22 includes a number of additions to the language, including require()ing ES modules, as well as changes to the runtime implementation and the standard library. With this release, Node.js developers can take advantage of these new features and enhancements when creating serverless applications on Lambda.

You can develop Node.js 22 Lambda functions using the AWS Management ConsoleAWS Command Line Interface (AWS CLI)AWS SDK for JavaScriptAWS Serverless Application Model (AWS SAM)AWS Cloud Development Kit (AWS CDK), and other infrastructure as code tools.

To use this new version, specify a runtime parameter value of nodejs22.x when creating or updating functions or by using the appropriate container base image.

You can use Node.js 22 with Powertools for AWS Lambda (TypeScript), a developer toolkit to implement serverless best practices and increase developer velocity. Powertools for AWS Lambda includes libraries to support common tasks such as observability, AWS Systems Manager Parameter Store integration, idempotency, batch processing, and more. You can also use Node.js 22 with Lambda@Edge to customize low-latency content delivered through Amazon CloudFront.

This blog post highlights important changes to the Node.js runtime, notable Node.js language updates, and how you can use the new Node.js 22 runtime in your serverless applications.

Node.js 22 language updates

Node.js 22 introduces several language updates and features that enhance developer productivity and improve application performance.

This release adds support for loading ECMAScript modules (ESM) using require(). You can enable this feature using the --experimental-require-module flag by configuring the NODE_OPTIONS environment variable. require() support for synchronous ESM graphs bridges the gap between CommonJS and ESM, providing more flexibility in module loading. It is important to note that this feature is currently experimental and may change in future releases.

WebSocket support which was previously available behind the --experimental-websocket flag is now enabled by default in Node.js 22. This brings a browser-compatible WebSocket client implementation to Node.js with no need for external dependencies. Native support simplifies building real-time applications and enhances the overall WebSocket experience in Node.js environments.

The new runtime also includes performance improvements to AbortSignal creation. This makes network operations faster and more efficient for the Fetch API and test runner. The Fetch API is also now considered stable in Node.js 22.

For TypeScript users, Node.js 22 introduces experimental support for transforming TypeScript-only syntax into JavaScript code. By using the --experimental-transform-types flag, you can enable this feature to support TypeScript syntax such as Enum and namespace directly. While you can enable the feature in Lambda, your function entrypoint (i.e. index.mjs or app.cjs) cannot currently be written using TypeScript as the runtime expects a file with a JavaScript extension. You can use TypeScript for any other module imported within your codebase.

For a detailed overview of Node.js 22 language features, see the Node.js 22 release blog post and the Node.js 22 changelog.

Experimental features that are unavailable

Node.js 22 includes an experimental feature to detect the module syntax automatically (CommonJS or ES Modules). This feature must be enabled when the Node.js runtime is compiled. Since the Lambda-provided Node.js 22 runtime is intended for production workloads, this experimental feature is not enabled in the Lambda build and cannot be enabled via an execution-time flag. To use this feature in Lambda, you need to deploy your own Node.js runtime using a custom runtime or container image with experimental module syntax detection enabled.

Performance considerations

At launch, new Lambda runtimes receive less usage than existing established runtimes. This can result in longer cold start times due to reduced cache residency within internal Lambda sub-systems. Cold start times typically improve in the weeks following launch as usage increases. As a result, AWS recommends not drawing conclusions from side-by-side performance comparisons with other Lambda runtimes until the performance has stabilized. Since performance is highly dependent on workload, customers with performance-sensitive workloads should conduct their own testing, instead of relying on generic test benchmarks.

Builders should continue to measure and test function performance and optimize function code and configuration for any impact. To learn more about how to optimize Node.js performance in Lambda, see Performance optimization in the Lambda Operator Guide, and our blog post Optimizing Node.js dependencies in AWS Lambda.

Migration from earlier Node.js runtimes

AWS SDK for JavaScript

Up until Node.js 16, Lambda’s Node.js runtimes included the AWS SDK for JavaScript version 2. This has since been superseded by the AWS SDK for JavaScript version 3, which was released in December 2022. Starting with Node.js 18, and continuing with Node.js 22, the Lambda Node.js runtimes include version 3. When upgrading from Node.js 16 or earlier runtimes and using the included version 2, you must upgrade your code to use the v3 SDK.

For optimal performance, and to have full control over your code dependencies, we recommend bundling and minifying the AWS SDK in your deployment package, rather than using the SDK included in the runtime. For more information, see Optimizing Node.js dependencies in AWS Lambda.

Amazon Linux 2023

The Node.js 22 runtime is based on the provided.al2023 runtime, which is based on the Amazon Linux 2023 minimal container image. The Amazon Linux 2023 minimal image uses microdnf as a package manager, symlinked as dnf. This replaces the yum package manager used in Node.js 18 and earlier AL2-based images. If you deploy your Lambda function as a container image, you must update your Dockerfile to use dnf instead of yum when upgrading to the Node.js 22 base image from Node.js 18 or earlier.

Additionally AL2 includes curl and gnupg2 as their minimal versions curl-minimal and gnupg2-minimal.

Learn more about the provided.al2023 runtime in the blog post Introducing the Amazon Linux 2023 runtime for AWS Lambda and the Amazon Linux 2023 launch blog post.

Using the Node.js 22 runtime in AWS Lambda

AWS Management Console

To use the Node.js 22 runtime to develop your Lambda functions, specify a runtime parameter value Node.js 22.x when creating or updating a function. The Node.js 22 runtime version is now available in the Runtime dropdown on the Create function page in the AWS Lambda console:

Creating Node.js function in AWS Management Console

Creating Node.js function in AWS Management Console

To update an existing Lambda function to Node.js 22, navigate to the function in the Lambda console, then choose Node.js 22.x in the Runtime settings panel. The new version of Node.js is available in the Runtime dropdown:

Changing a function to Node.js 22

Changing a function to Node.js 22

AWS Lambda container image

Change the Node.js base image version by modifying the FROM statement in your Dockerfile.

FROM public.ecr.aws/lambda/nodejs:22
# Copy function code
COPY lambda_handler.xx ${LAMBDA_TASK_ROOT}

AWS Serverless Application Model (AWS SAM)

In AWS SAM, set the Runtime attribute to node22.x to use this version:

AWSTemplateFormatVersion: "2210-09-09"
Transform: AWS::Serverless-2216-10-31

Resources:
  MyFunction:
    Type: AWS::Serverless::Function
    Properties:
      Handler: lambda_function.lambda_handler
      Runtime: nodejs22.x
      CodeUri: my_function/.
      Description: My Node.js Lambda Function

When you add function code directly in an AWS SAM or AWS CloudFormation template as an inline function, it is seen as common.js.

AWS SAM supports generating this template with Node.js 22 for new serverless applications using the sam init command. Refer to the AWS SAM documentation.

AWS Cloud Development Kit (AWS CDK)

In AWS CDK, set the runtime attribute to Runtime.NODEJS_22_X to use this version.

import * as cdk from "aws-cdk-lib";
import * as lambda from "aws-cdk-lib/aws-lambda";
import * as path from "path";
import { Construct } from "constructs";

export class CdkStack extends cdk.Stack {
  constructor(scope: Construct, id: string, props?: cdk.StackProps) {
    super(scope, id, props);

    // The code that defines your stack goes here

    // The Node.js 22 enabled Lambda Function
    const lambdaFunction = new lambda.Function(this, "node22LambdaFunction", {
      runtime: lambda.Runtime.NODEJS_22_X,
      code: lambda.Code.fromAsset(path.join(__dirname, "/../lambda")),
      handler: "index.handler",
    });
  }
}


Conclusion

Lambda now supports Node.js 22 as a managed language runtime. This release uses the Amazon Linux 2023 OS as well as other improvements detailed in this blog post.

You can build and deploy functions using Node.js 22 using the AWS Management Console, AWS CLI, AWS SDK, AWS SAM, AWS CDK, or your choice of infrastructure as code tool. You can also use the Node.js 22 container base image if you prefer to build and deploy your functions using container images.

The Node.js 22 runtime helps developers build more efficient, powerful, and scalable serverless applications. Read about the Node.js programming model in the Lambda documentation to learn more about writing functions in Node.js 22. Try the Node.js runtime in Lambda today.

For more serverless learning resources, visit Serverless Land.

Introducing Amazon CloudFront VPC origins: Enhanced security and streamlined operations for your applications

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/introducing-amazon-cloudfront-vpc-origins-enhanced-security-and-streamlined-operations-for-your-applications/

I’m happy to introduce the release of Amazon CloudFront Virtual Private Cloud (VPC) origins, a new feature that enables content delivery from applications hosted in private subnets within their Amazon Virtual Private Cloud (Amazon VPC). This makes it easy to secure web applications, allowing you to focus on growing your businesses while improving security and maintaining high-performance and global scalability with CloudFront.

Customers serving content from Amazon Simple Storage Solution (Amazon S3), AWS Elemental Services and AWS Lambda Function URLs can use Origin Access Control as a managed solution to secure their origins, and make CloudFront the single front-door to your application. However, this was more difficult to achieve for applications that are hosted on Amazon Elastic Compute Cloud (Amazon EC2) or using load balancers, because you had to create your own solution to achieve the same result. You would have to use a combination of methods such as using access control lists (ACLs), managing firewall rules, or using logic such as header validation and a few other techniques to ensure that the endpoint remained exclusive to CloudFront.

CloudFront VPC origins removes the need for this kind of undifferentiated work by offering a managed solution that can be used to point CloudFront distributions directly to Application Load Balancers (ALBs), Network Load Balancers (NLBs), or EC2 instances inside your private subnets. This ensures that CloudFront becomes the sole ingress point for those resources with minimum configuration effort, providing you with improved performance and a cost-saving opportunity because it also eliminates the need for public IP addresses.

Configuring a CloudFront VPC origin
CloudFront VPC origins is available at no additional cost, making it an accessible option for all AWS customers. It can be integrated with new or existing CloudFront distributions using the Amazon CloudFront console or the AWS Command Line Interface (AWS CLI).

Imagine that you have an application hosted privately on an AWS Fargate for Amazon ECS fronted through an ALB. Let’s create a CloudFront distribution that uses the ALB directly inside the private subnet.

Start by navigating to the CloudFront console and select the new menu option: VPC origins.

vpc origins page

Creating a new VPC origin is straightforward. You only need to select from a few options. In the Origin ARN, you can search for available resources that are hosted in private subnets or enter it directly. You select the resources that you want, choose a friendly name for your VPC origin alongside some security options, and then confirm. Please note that, at launch, the VPC origin resource must be in the same AWS Account as the CloudFront distribution, although support for resources across all accounts is coming soon.

creating a vpc origin

After the creation process is complete, your VPC origin will be deployed and ready to go! You can check its status on the VPC origins page.

With this, we have created a CloudFront distribution that serves content directly from a resource hosted on a private subnet in a few clicks! After your VPC origin is created, you can navigate to your Distribution window, and add the VPC origin to your Distribution by either selecting the ARN from the dropdown or copy-pasting the ARN manually.

Remember, though, that it’s important to still continue to layer your application’s security by using services such as AWS Web Application Firewall (WAF) to protect from web exploits, or AWS Shield for managed DDos protection, and other services to achieve a full-spectrum protection.

Conclusion
CloudFront VPC Origins offers a new way for organizations to deliver secure, high-performance applications by enabling CloudFront distributions to serve content directly from resources hosted within private subnets. This reduces the complexity and cost of maintaining public-facing origins while ensuring that your application remains secure.

To learn more, see the getting started guide.

Matheus Guimaraes | @codingmatheus

Amazon CloudFront now accepts your applications’ gRPC calls

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-cloudfront-now-accepts-your-applications-grpc-calls/

Starting today, you can deploy Amazon CloudFront, our global content delivery network (CDN), in front of your gRPC API endpoints.

gRPC is a modern, efficient, and language-agnostic framework for building APIs. It uses Protocol Buffers (protobuf) as its interface definition language (IDL), which enable you to define services and message types in a platform-independent manner. With gRPC, communication between services is achieved through lightweight and high-performance remote procedure calls (RPCs) over HTTP/2. This promotes efficient and low-latency communication across services, making it ideal for microservices architectures.

gRPC offers features such as bidirectional streaming, flow control, and automatic code generation for a variety of programming languages. It’s well-suited for scenarios in which you require high performance, efficient communication, and real-time data streaming. If your application needs to handle a large amount of data or requires low-latency communication between client and server, gRPC can be a good choice. However, gRPC might be more challenging to learn compared to REST. For example, gRPC relies on the protobuf serialization format, which requires developers to define their data structures and service methods in .proto files.

I see two benefits of deploying CloudFront in front of your gRPC API endpoints.

First, it allows the reduction of latency between the client application and your API implementation. CloudFront offers a global network of over 600+ edge locations with intelligent routing to the closest edge. Edge locations provide TLS termination and optional caching for your static content. CloudFront transfers client application requests to your gRPC origin through the fully managed, low-latency, and high-bandwidth private AWS network.

Secondly, your applications benefit from additional security services deployed on edge locations, such as traffic encryption, the validation of the HTTP headers through AWS Web Application Firewall, and AWS Shield Standard protection against distributed denial of service (DDoS) attacks.

Let’s see it in action
To start this demo, I use the gRPC route-guide demo from the official gRPC code repository. I deploy this example application in a container for ease of deployment (but any other deployment option is supported too).

I use this Dockerfile

FROM python:3.7
RUN pip install protobuf grpcio
COPY ./grpc/examples/python/route_guide .
CMD python route_guide_server.py
EXPOSE 50051

I also use the AWS Copilot command line to deploy my container on Amazon Elastic Container Service (Amazon ECS). The Copilot command prompts me to collect the information it requires to build and deploy the container. Then, it creates the ECS cluster, the ECS service, and the ECS task automatically. It also creates a TLS certificate and the load balancer for me. I test the client application by modifying line 122 to use the DNS name of the load balancer listener endpoint. I also change the client application code to use grpc.secure_channel instead of grpc.insecure_channel because the load balancer provides the application with an HTTPS endpoint.

gRPC client application demo - source code with ALB

When I’m confident my API is correctly deployed and working, I proceed and configure CloudFront.

First, in the CloudFront section of the AWS Management Console, I select Create distribution.

Under Origin, I enter my gRPC endpoint DNS name as Origin domain. I enable HTTPS only as Protocol and leave the HTTPS port as is (443). Then I choose a Name for the distribution.

CloudFront - Add origin and name

Under Viewer, I select HTTPS only as Viewer protocol policy. Then, I select GET, HEAD, OPTIONS, PUT, POST, PATCH, DELETE as Allowed HTTP methods. I select Enable for Allow gRPC requests over HTTP/2.

CloudFront - Viewer Policy

Under Cache key and origin requests, I select AllViewer as Origin request policy.

The default cache policy is CacheOptimized, but gRPC isn’t cacheable API traffic. Therefore, I select CachingDisabled as Cache policy.

CloudFront - Cache policy

AWS WAF helps protect you against common web exploits and bots that can affect availability, compromise security, or consume excessive resources. For gRPC traffic, AWS WAF can inspect the HTTP headers of the request and enforce access control. It doesn’t inspect the request body in protobuf format.

For this demo, I choose to not use AWS WAF. Under Web Application Firewall (WAF), I select Do not enable security protections.

CloudFront - Security

I also keep all the other options with their default value. HTTP/2 support is selected by default. Do not disable it because it is required for gRPC.

Finally, I select Create distribution.

CloudFront - Create distribution

There is only one switch to enable gRPC on top of the usual setup. When turned on, with HTTP/2 and HTTP POST enabled, CloudFront detects gRPC client traffic and forwards it to your gRPC origin.

After a few minutes, the distribution is ready. I copy and paste the endpoint URL of the CloudFront distribution, and I change the client-side app to make it point to CloudFront instead of the previously created load balancer.

gRPC client application demo - source code

I test the application again, and it works.

gRPC client application demo - execution

Pricing and Availability
gRPC origins are available on all the more than 600 CloudFront edge locations at no additional cost. The usual requests and data transfer fees apply.

Go and point your CloudFront origin to a gRPC endpoint today.

— seb

A new AWS CDK L2 construct for Amazon CloudFront Origin Access Control (OAC)

Post Syndicated from Josh DeMuth original https://aws.amazon.com/blogs/devops/a-new-aws-cdk-l2-construct-for-amazon-cloudfront-origin-access-control-oac/

Recently, we launched a new AWS Cloud Development Kit (CDK) L2 construct for Amazon CloudFront Origin Access Control (OAC). This construct simplifies the configuration and maintenance of securing Amazon Simple Storage Service (Amazon S3) CloudFront origins with CDK. Launched in 2022, OAC is the recommended way to secure your CloudFront distributions due to additional security features compared to the legacy Origin Access Identity (OAI). This new construct makes it easier for you to use the latest origin access best practices to build and manage your CloudFront distributions.

CDK is an open-source software development framework for defining cloud infrastructure in code and provisioning it through AWS CloudFormation. A primary part of CDK is the AWS CDK Construct Library which is a collection of pre-written constructs. Constructs are the basic building blocks of CDK applications. They help reduce the complexity required to define and integrate AWS services together.

There are different levels of constructs, starting with Level 1 (L1) which map directly to a single CloudFormation resource and offer no abstraction. L1 constructs are auto-generated, which means you can build any CloudFormation resource using CDK. The power of the CDK starts with Level 2 (L2) and higher constructs. L2 constructs, also known as curated constructs, are developed by the CDK team and provide a higher-level abstraction through an intuitive intent-based API. You can read more about constructs and their benefits in the CDK user guide.

In this post we’ll explore:

  • The reasoning behind the creation of a new L2 construct for OAC
  • How to use the new OAC construct
  • How to migrate from the legacy OAI construct to the new OAC construct

Background

Amazon CloudFront is a global content delivery network that reduces latency by delivering data to viewers anywhere in the world. CloudFront can connect to different types of locations or origins, such as S3, AWS Lambda function URLs, and custom origins. A full list of supported origins can be found in the CloudFront user guide.

At launch, the new L2 construct supports OAC with S3 origins. Using OAC with S3 allows you to keep your S3 bucket private, yet accessible, through CloudFront. This forces users to access content only through CloudFront where other security features can be applied, like AWS WAF.

There are two ways to restrict buckets to only CloudFront, using OAI (legacy) or OAC (recommended). Both OAI and OAC allow you to secure your buckets, but OAC offers additional benefits, including support for:

  • Any new AWS Regions launched after December 2022
  • Amazon S3 server-side encryption with AWS Key Management Service (SSE-KMS)
  • Dynamic requests (PUT and DELETE) to Amazon S3
  • Enhanced security practices like short term credentials, frequent credential rotations, and resource-based policies

Prior to this release, customers had to piece together L1 constructs as well as use escape hatches in order to implement OAC.

The introduction of the new L2 construct simplifies the process by enhancing abstraction and reducing complexity. It makes it easy to use OAC while still offering the flexibility to customize all existing properties available by building with L1’s.

Let’s see the construct in action!

Using the L2

We modified the existing CloudFront Origins L2 to add OAC support. With this change, the S3Origin class has been deprecated in favor of S3BucketOrigin for standard S3 origins, and S3StaticWebsiteOrigin for static website S3 origins.

Using OAC with a standard S3 origin is as simple as passing your bucket as a parameter to the new S3BucketOrigin class using the withOriginAccessControl method.

In the example below, we define a private bucket and let the new L2 construct handle all the OAC configuration for us.

const s3bucket = new s3.Bucket(this, "myBucket", {
    bucketName: `${cdk.Stack.of(this).stackName.toLowerCase()}-oacbucket`,
    blockPublicAccess: s3.BlockPublicAccess.BLOCK_ALL,
    accessControl: s3.BucketAccessControl.PRIVATE,
    enforceSSL: true,
});

const distribution = new cloudfront.Distribution(this, "myDist", {
    defaultBehavior: {
        origin: origins.S3BucketOrigin.withOriginAccessControl(s3bucket),
    }
});

This code defines a S3 bucket configured to block all public access, enforces SSL, and uses private access control. It also defines a CloudFront distribution with the S3 bucket as its origin using the default OAC settings from the OAC construct. By default, the signing behavior is set to “always” and the signing protocol to “sigv4” as is shown below:

Showing the default signing behavior settings for Amazon CloudFront when using the default properties for the L2 construct

Figure 1 – Default OAC Settings for the S3 Origin

In typical CDK fashion, the L2 provides sane defaults out-of-the-box but allows you to customize. Some examples of customizing with the L2, include:

  • Changing the signing behavior
  • Granting permissions for dynamic requests (write/delete access)
  • Migrating to the new construct but continuing to use OAI

S3 Origin with Customer Managed KMS

It is a recommended security best practice to encrypt S3 objects at rest. As detailed in the S3 user guide, using SSE-KMS gives you additional flexibility to meet encryption-related compliance requirements.

If using SSE-KMS, CloudFront must have permission to at least decrypt objects using your AWS KMS key. With the new changes, simply configure your bucket to use an AWS KMS key and the construct will take care of the permissions updates.

The following example shows how to create an SSE-KMS encrypted S3 bucket and use it as a CloudFront origin with OAC:

  1. Create an AWS KMS Key.
  2. Create the S3 Bucket with the encryptionKey property set to the AWS KMS key and encryption as KMS.
  3. Create the CloudFront distribution and use the new S3BucketOrigin class with OAC.
const kmsKey = new kms.Key(this, "myKey");

const myBucket = new s3.Bucket(this, 'myEncryptedBucket', {
  encryption: s3.BucketEncryption.KMS,
  encryptionKey: kmsKey,
  objectOwnership: s3.ObjectOwnership.BUCKET_OWNER_ENFORCED,
}); 

new cloudfront.Distribution(this, 'myDist', {
  defaultBehavior: { 
    origin: origins.S3BucketOrigin.withOriginAccessControl(myBucket) 
  },
});

Due to circular dependencies between the bucket, the KMS key, and the CloudFront distribution, when we synthesize the above code, a warning message similar to the following may appear:

To avoid a circular dependency between the KMS key, Bucket, and Distribution during the initial deployment, a wildcard is used in the Key policy condition to match all Distribution IDs.

After the initial deployment, it is recommended to further restrict the policy to adhere to security best practices. Here is an example of how to use an escape hatch to update the policy:

Note: update the existing KMS Key policy to include the statements in scopedDownKeyPolicy

const scopedDownKeyPolicy = {
    Version: "2012-10-17",
    Statement: [
        {
            Effect: "Allow",
            Principal: {
                AWS: `arn:aws:iam::${this.account}:root`,
            },
            Action: "kms:*",
            Resource: "*",
        },
        {
            Effect: "Allow",
            Principal: {
                Service: "cloudfront.amazonaws.com",
            },
            Action: ["kms:Decrypt", "kms:Encrypt", "kms:GenerateDataKey*"],
            Resource: "*",
            Condition: {
                StringEquals: {
                    "AWS:SourceArn": `arn:aws:cloudfront::${this.account}:distribution/<Distribution ID>`//replace <Distribution ID> with the ID of the deployed CloudFront Distribution 
                },
            },
        },
    ],
};

const cfnKey = kmsKey.node.defaultChild as kms.CfnKey;
cfnKey.addOverride("Properties.KeyPolicy", scopedDownKeyPolicy);

For detailed instructions on how to update the AWS KMS key policy, please refer to the “Scoping down the key policy” section in the CDK API docs.

Considerations when migrating to the new construct

If you have an existing OAI implementation using the now-deprecated S3Origin class, switching to OAC has potential for application downtime. CloudFront could temporarily lose access to the S3 bucket while the CloudFormation is deploying.

To avoid downtime, it is recommended to perform the upgrade across multiple deployments. This will explicitly give CloudFront permissions to both OAC and OAI in the S3 bucket policy before the migration is performed.

At a high level, the three steps are:

  • Deployment 1: update the bucket policy to explicitly allow CloudFront access
  • Deployment 2: switch to the new construct
  • Deployment 3: optionally remove the code that updated the bucket policy in step 1

For detailed instructions, see the Migrating from OAI to OAC section of the CDK API docs.

Conclusion

In this post, we introduced the new AWS CDK L2 construct for Amazon CloudFront Origin Access Control (OAC), highlighting the advantages of using OAC instead of OAI to secure your Amazon S3 CloudFront origins. We showcased practical implementations of the new construct, focusing on using defaults of the L2 construct along with how to customize for your use case.

To summarize, the new L2 construct and OAC offers these benefits:

  • Simplified configuration: the L2 construct simplifies the process of configuring OAC in your CDK application to set up secure access controls between CloudFront and S3 buckets
  • Using SSE-KMS encryption: the L2 construct will automatically add the IAM policy statement to the AWS KMS key to allow access to OAC
  • Ability to customize: the L2 construct offers properties to override defaults, like changing the signing behavior
  • Easily migrate from OAI to OAC: the L2 construct offers options to migrate from OAI to OAC based on your application’s downtime tolerance

At launch, the construct supports an Amazon S3 origin. If there is a particular origin that you are looking to see added to the construct library for OAC, please submit a feature request issue in the aws-cdk GitHub repo. For example, if you are interested in Lambda support for OAC, add your feedback to this feature request.

If you’re new to CDK and want to get started, we highly recommend checking out the CDK documentation and the CDK workshop.

Josh DeMuth

Josh DeMuth is a Senior Solutions Architect with the Consulting Partner SA team at Amazon Web Services. He provides technical guidance to AWS Partners helping build solutions on AWS. He specializes in Infrastructure as Code, and loves the CDK!

JJ Lei

JJ Lei is a Solutions Architect with the Consulting Partner SA team at Amazon Web Services. He provides technical guidance to AWS Partners developing AWS practices, specializing in Infrastructure as Code and has a particular fondness for the CDK. In his free time, he enjoys playing video games and taking long walks in large parks with a sizable backpack.