Security updates for Thursday

Post Syndicated from jzb original https://lwn.net/Articles/1090938/

Security updates have been issued by AlmaLinux (assertj-core, attr, firefox, go-toolset:rhel8, golang, grafana, gstreamer1-plugins-good, httpd, kernel, mingw-openssl, mod_http2, nginx, nginx:1.24, pam, polkit, and sqlite), Debian (bubblewrap, cockpit, emacs, gimp, libdbi-perl, openjdk-11, openjdk-17, wireshark, and xrdp), Fedora (bluez, curl, emacs, golang, knot, libopenmpt, libsoup3, openbao, openssh, rsync, rust-anstyle-hyperlink, rust-anstyle-progress, rust-cargo, rust-cargo-c, rust-cargo-credential-libsecret, rust-cargo-util, rust-cargo-util-schemas, rust-cargo-util-terminal, rust-crates-io, and rust-rustfix), Gentoo (Chromium, Google Chrome, Microsoft Edge, Opera, Chromium, Google Chrome, Microsoft Edge, Opera, Vivaldi, Chromium, Google Chrome, Microsoft Edge. Opera, and OpenRGB), Oracle (abrt, assertj-core, attr, gstreamer1-plugins-base, gstreamer1-plugins-good, httpd, nginx:1.24, nginx:1.26, nodejs24, and polkit), SUSE (apache2-mod_auth_openidc, buildah, curl, docker, dracut, evince, go1.25-openssl, go1.26-openssl, go1.27, gstreamer-plugins-bad, kernel, kubernetes, kubernetes-old, libarchive, LibVNCServer, libwireshark19, pcp, python310-pip, qemu, rootlesskit, rsync, snpguest, and util-linux), and Ubuntu (bind9, libheif, and openssl, openssl1.0).

LLM-Based Social Engineering Scams

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/llm-based-social-engineering-scams.html

OpenAI disrupted a social engineering group from Cambodia that used ChatGPT. Its scope is impressive:

The network simultaneously conducted multiple types of scams, often blending elements from different schemes. For instance, operators used dating personas to build trust before introducing fraudulent investment opportunities involving cryptocurrencies and spot gold trading. Other users engaged in lengthy romantic conversations with targets using fictitious identities, posed as representatives of online gambling platforms offering fake bonuses and winnings, or impersonated law enforcement agencies to tell targets they needed to pay fines for committing serious criminal offenses.

Although the narratives varied, users across the network consistently displayed the same underlying pattern of deceptive behavior. For example, they created and operated fake dating profiles, fictitious investment experts, and fraudulent law enforcement personas. They also generated images of forged documents, including passports, legal notices, stock-purchase confirmations, and gambling platform interfaces.

ICYMI: July 2026 @AWS Security

Post Syndicated from Rodolfo Brenes original https://aws.amazon.com/blogs/security/icymi-july-2026-aws-security/

If you found time for a bit of vacation this summer, you might be in catch-up mode. Here’s a list to help: all the expert blog posts, new service capabilities, code samples, and workshops, in case you missed it, from July 2026.

AWS Security Blog post

This month’s AWS Security Blog posts covered AI agent security, supply chain protection, network firewall automation, DDoS mitigation, and compliance readiness. Read on for guidance on securing AI coding agents, implementing dependency cooldowns, choosing the right key management solution, and preparing for HIPAA Technical Safeguard requirements.

AI Security

Enforce least-privilege authorization in multi-agent AI chains using Cedar
Authors: Dhananjay Karanjkar | Published: July 6, 2026
Learn to implement a three-layer Cedar policy model with OAuth 2.0 authentication to prevent authorization scope expansion across multi-agent delegation chains using Amazon Verified Permissions.

Enforce zero data retention on Amazon Bedrock with Bedrock Projects and service control policies
Author: Rob Higareda | Published: July 7, 2026
Learn to use Amazon Bedrock Projects and SCPs to centrally enforce zero data retention policies, preventing accounts from enabling data sharing with third-party model providers across your organization.

Designing for the inevitable: System prompt leakage and mitigations in generative AI applications
Author: Manideep Konakandla | Published: July 8, 2026
Learn to implement defense-in-depth mitigations for system prompt leakage using Amazon Bedrock Guardrails prompt attack filters, canary tokens, semantic similarity detection, and sandwich instruction patterns.

Balancing speed and safety: A control framework for AI coding agents
Authors: Daniel Begimher, Danny Cortegaca | Published: July 30, 2026
Learn to implement an application security control framework for AI coding agents, with author-time controls that shape what agents produce and build-time controls that verify what reaches production.

Data Protection

How to use the AWS Workload Credentials Provider for cross-account secret retrieval and prefetching secrets
Authors: Derik Wang, Paras Dhawan | Published: July 1, 2026
Learn to configure the AWS Workload Credentials Provider for cross-account secret retrieval using IAM role chaining and prefetching secrets at startup to reduce cold-start latency.

The CISO’s guide to post-quantum mandates and migrations
Author: Rushir Patel | Published: July 8, 2026
A strategic playbook for CISOs navigating post-quantum cryptography migration, covering regulatory timelines, dependency classification, cryptographic telemetry, and building crypto-agile organizations.

AWS KMS or AWS CloudHSM: Choose the right key management solution
Author: Derek Tumulak | Published: July 28, 2026
Learn how to choose between AWS KMS and AWS CloudHSM based on integration needs, cost, and whether you require traditional HSM interfaces or legacy algorithms.

Secure your npm and pip package updates in Amazon Linux
Author: Norbert Manthey | Published: July 29, 2026
Learn to implement a one-line dependency cooldown for npm and pip that skips packages published in the last 24 hours, protecting against supply chain events while still allowing urgent security patches.

Infrastructure security

Secure Amazon container workloads using container attribute-based rules in AWS Network Firewall
Authors: Amit Gaur, Amish Shah, Preetkumar Shah, Akash Kumar Sinha | Published: July 1, 2026
Learn to define AWS Network Firewall rules for Amazon EKS and Amazon ECS workloads using native container attributes like namespaces, pod names, and labels instead of ephemeral IP addresses.

Authenticate legitimate AI agent traffic with AWS WAF Bot Control
Authors: Harith Gaddamanugu, Kaustubh Phatak | Published: July 14, 2026
Learn to use Web Bot Authentication (WBA) in AWS WAF Bot Control to cryptographically verify legitimate AI agent traffic using HTTP message signatures and ed25519 keys.

Accelerating AWS Network Firewall troubleshooting with AWS DevOps Agent
Author: Salman Ahmed | Published: July 24, 2026
Learn to use AWS DevOps Agent to automate root cause analysis for AWS Network Firewall connectivity issues, including domain deny lists, stateless rule priority misconfigurations, and asymmetric cross-AZ routing drops.

AWS Shield Advanced is embracing the AWS WAF Anti-DDoS managed rule group: What changes and how to prepare
Authors: Eitav Arditti, Andrew Chen, Justin Kurpius | Published: July 27, 2026
AWS Shield Advanced is adopting the AWS WAF Anti-DDoS managed rule group as its default application-layer DDoS protection, with a phased migration from July 2026 through January 2027.

Threat detection and incident response

Introducing the Amazon GuardDuty investigation agent: on-demand AI-powered threat assessment
Author: Allan Holmes | Published: July 20, 2026
Learn to use the new Amazon GuardDuty investigation agent (public preview) to automate threat correlation and receive structured assessments with risk levels, confidence scores, MITRE ATT&CK mappings, and actionable recommendations.

Amazon identifies North Korean hacker group behind open-source supply chain attacks
Author: CJ Moses | Published: July 29, 2026
Learn how Amazon Threat Intelligence linked the compromises of axios, debug, chalk, and typo-crypto NPM packages to a single DPRK-linked threat actor, and how attacker tradecraft is evolving with generative AI.

Extend Amazon Inspector SBOM Generator with plugins
Authors: Michael Long, Anthony Verleysen, Charlie Bacon | Published: July 30, 2026
Learn to write custom Lua plugins for the Amazon Inspector SBOM Generator to inventory package ecosystems that aren’t supported out of the box, without modifying source code or waiting for an official release.

Security Hub adds AI workload protection and multicloud support for Microsoft Azure
Author: Michael Fuller | Published: July 14, 2026
AWS Security Hub now monitors Microsoft Azure resources for misconfigurations and vulnerabilities, adds GuardDuty AI Protection for Amazon Bedrock and Amazon SageMaker AI, and introduces an AI inventory for organization-wide visibility.

Governance and compliance

AWS designated as a critical third party to the UK financial sector
Author: Michael Jefferson | Published: July 10, 2026
AWS has been designated as a critical third party to the UK financial sector by HM Treasury, establishing direct regulatory oversight by the Bank of England, PRA, and FCA.

New compliance guidance available: HITRUST i1 on AWS
Authors: Abdul Javid, Shreya Singh | Published: July 13, 2026
AWS published new implementation guidance for HITRUST i1 certification, covering 11 technical control domains with AWS-specific controls for healthcare organizations seeking i1 assessment readiness.

HIPAA Security Rule on AWS – Technical Safeguards Implementation and Readiness Guidance
Authors: Abdul Javid, Hector Rodriguez, Kapil Temghare, Shreya Singh | Published: July 31, 2026
New guidance helping covered entities and business associates implement and evidence compliance with HIPAA Security Rule Technical Safeguards (§164.312) on AWS, including 2025 NPRM proposed changes.

Identity

Introducing OAuth support for AWS MCP Server
Authors: Vaibhav Chowla, Jaimin Bhatt, Ankur Joshi | Published: July 9, 2026
AWS MCP Server now supports OAuth 2.1 authorization through AWS Sign-In, enabling agents like Claude Code,Kiro, and Gemini CLI to connect using existing IAM credentials with browser-based authentication.

July Security Bulletins

In July 2026, AWS published 21 security bulletins (2026-049 through 2026-069) addressing vulnerabilities across open-source SDKs, MCP servers, and developer tools. Key themes include credential disclosure and SSRF, affecting HealthLake, HealthOmics, and API MCP servers, plus Strands Agents tools that could inadvertently expose secrets to unauthorized endpoints. Command and code injection impacted aws-cdk-lib, jsii-diff, Bedrock AgentCore SDK, and Amplify Codegen UI. The smithy-rs framework received three patches for denial-of-service via uncontrolled recursion and Slowloris issues.

Other notable issues include insecure file permissions in the AWS CLI, deserialization remote code execution in the Advanced JDBC Wrapper, SQL injection in mcp-gateway-registry, TLS 1.3 flaws in s2n-tls, and stored XSS in AWS Ops Wheel. A common thread: insufficient input validation in tools interacting with AI agents, reflecting the expanded surface area of LLM-integrated workflows. All patches are available, upgrade promptly. For more information, see AWS Security Bulletins.

AWS Samples

This month brings 14 new AWS samples spanning AI security, identity, data protection, governance, threat detection, and security posture management. From deploying governed AI agent platforms on Amazon Bedrock AgentCore to building data-residency-compliant chatbots and DevSecOps baselines for Kiro, these repositories help you implement security and governance best practices across your AWS environment.

AI Security

Lark MCP on AgentCore
Learn to deploy a hosted remote MCP service on Amazon Bedrock AgentCore that lets AI agents operate Feishu/Lark through 450+ tools, with per-user identity isolation and smart multi-step orchestration via 20+ domain Skills.

Lark CLI MCP Wrapper on AgentCore Runtime and Identity
Learn to securely wrap a CLI tool as an MCP server on AgentCore Runtime using a sidecar credential-isolation pattern, where the CLI process never holds real tokens and all secrets are resolved through AgentCore Identity’s Token Vault.

LiteLLM Bedrock Gateway on EKS
Learn to deploy a production-grade LiteLLM proxy on Amazon EKS as a unified OpenAI/Anthropic-compatible gateway to Amazon Bedrock, with four progressive layers covering network isolation, cross-region inference profiles, and cross-account delegation.

Enterprise Agentic AI Platform Accelerator on AgentCore
Learn to deploy a secure, governed foundation for production AI agents on Amazon Bedrock AgentCore with CDK stacks covering identity, gateway, memory, runtime, and observability; supporting multiple agent frameworks (Strands, LangGraph, Claude SDK) and opt-in security controls including VPC isolation, KMS encryption, Cedar policies, and Bedrock Guardrails.

FlowAMP: AI Agent Governance on AWS
Learn to deploy a single-pane-of-glass agent management platform on Amazon Bedrock AgentCore that discovers, monitors, scores, controls, and cost-accounts AI agents across an AWS Organization with agentic discovery, compliance scanning (NIST AI RMF, ISO 27001, SOC 2), Responsible-AI scoring, FinOps via Cost Explorer, and Cedar-based policy enforcement.

Kiro SecOps Baseline
Learn to deploy a DevSecOps security baseline for Kiro as a single Go CLI that installs global guardrails (permissions.yaml, steering, skills, a security-review agent) and per-project workspace hooks (fail-closed guard, PR/pipeline review gates, scanner configs for gitleaks, trivy, and checkov) with enterprise fleet distribution via MDM and Administration scope.

Identity

OAuth 2.0 Token Exchange with Amazon Cognito
Learn to implement RFC 8693 OAuth 2.0 Token Exchange using Amazon Cognitowith a true delegation pattern, enabling services to act on behalf of users while maintaining distinct service identities and least-privilege access in microservices architectures.

Lark Identity on AgentCore — Gateway Interceptor
Learn to implement enterprise identity pass-through on Amazon Bedrock AgentCore using a Gateway Request Interceptor that forwards the user’s identity and injects per-user credentials to downstream MCP tools, so the agent never holds a token and tools act only as the authenticated user against Lark.

Data Protection

Automated PII Detection Pipeline with Amazon Macie
Learn to build an event-driven pipeline that automatically detects PII in Amazon S3 objects using Amazon Macie, AWS Step Functions, and custom data identifiers, with CSV/JSON reporting and SNSalerting for high-severity findings.

Data-Residency Chatbot with Amazon Bedrock AgentCore
Learn to build a data-residency-compliant natural-language chatbot on Amazon Bedrock AgentCore that keeps all data and AI inference within a single AWS Region, using governed text-to-SQL with whitelist-validated queries, Aurora PostgreSQL in private subnets, and AgentCore Gateway for secure tool access.

Governance and compliance

Video Compliance Agent
Learn to build an end-to-end automated video compliance verification pipeline using Amazon Bedrock, ECS Fargate, and AWS Step Functions that processes videos shot-by-shot, extracting frames, audio transcripts, and OCR text, then flags potential broadcast guideline violations with structured per-shot reports.

Contract Compliance Search with Amazon OpenSearch
Learn to build a contract compliance search system that combines semantic search with semantic highlighting using Amazon OpenSearchService, Amazon Titan V2 embeddings, and a SageMaker-hosted highlighting model to surface relevant clauses across contract documents.

Threat detection and incident response

Multicloud Security Posture Assessment
Learn to deploy a centralized security assessment solution that scans AWS, Azure, Google Cloud Platform, and Oracle Cloud Infrastructure environments from a single AWS deployment using Prowler, with AWS CloudFormation templates for each provider and unified reporting in HTML, CSV, and JSON-OCSF formats.

Centralize AWS Security Agent Findings
Learn to deploy a AWS CloudFormation stack that automatically exports AWS Security Agentpenetration test findings to Amazon S3 and queries them centrally with Amazon Athena, using Amazon EventBridge, Step Functions, and a AWS Glue catalog for tracking findings over time.

Sentinel Harness — Production SecOps Agents as Configuration
Learn to build production security-operations agents as pure configuration on Amazon Bedrock AgentCore Harness, declaring model, prompt, tools, skills, memory, and limits in YAML while AWS runs the agent loop with human-in-the-loop gates, detection-engineering tools, adversary emulation, and a self-improvement closed loop.

AWS Labs

This month brings 1 new AWS Labs repository focused on data protection, helping organizations build automated PII detection and redaction pipelines with AI-powered processing across documents and audio files.

Data Protection

PII Anonymizer
Learn to build an automated PII detection and redaction pipeline using AWS Step Functions, Amazon Bedrock, Amazon Textract, and Amazon Transcribe; supporting PDFs, Word, Excel, images, and audio files with synthetic replacement or blackout modes, concurrency control, and customer-managed KMS encryption.

Conclusion

July 2026 provides guidance and examples for securing AI agent architectures at scale, from governed text-to-SQL with data residency controls and agent management platforms to DevSecOps baselines for AI coding tools. The posts and samples provide patterns for least-privilege authorization in multi-agent chains using Cedar, post-quantum migration planning, container-aware network firewall rules, and multicloud security posture management. Each resource includes deployment steps or runnable code so you can validate in your own environment before adopting. Subscribe to the AWS Security Blog RSS feed to receive updates as they publish, and revisit this digest monthly for a consolidated view of what changed and what to act on.

If you have feedback about this post, submit comments in the Comments section below.


Rodolfo Brenes

Rodolfo Brenes

Rodolfo is a Principal Solutions Architect focused on Cloud Governance and Compliance. With over 18 years of experience, he currently leads a technical field community in AWS helping customers scale and improve their security and governance frameworks. Besides work, Rodolfo enjoys video games, playing with his four cats, and won’t say no to a good outdoor adventure.

Anna Brinkmann

Anna has 18 years of experience in the technical content space and has spent the last 6 years managing the AWS Security Blog. Outside of work, she enjoys spending time with her family.

Migrate an OAuth 2.0 authenticated Apache Kafka cluster to Amazon MSK with MSK Replicator

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/migrate-an-oauth-2-0-authenticated-apache-kafka-cluster-to-amazon-msk-with-msk-replicator/

In an earlier post, we walked through how Amazon Managed Streaming for Apache Kafka (Amazon MSK) Replicator migrates external and self-managed Apache Kafka clusters to Amazon MSK. It replicates your topics and their configurations, keeps topic and consumer-group names intact, and synchronizes consumer-group offsets, so your producers and consumers can cut over on their own schedule instead of all at once. MSK Replicator now supports OAuth 2.0 (SASL/OAUTHBEARER) authentication to the external cluster, and that is what this post covers.

If your external Kafka cluster authenticates clients with OAuth, MSK Replicator can connect to it, but “OAuth” isn’t a single thing you switch on. It’s a family of grant types, and each one comes with its own trust model, its own set of inputs you need to supply, and its own configuration on both the Replicator side and your identity provider (IdP) side.

In this post, we walk you through the grant types one by one, show you how to configure Replicator for each, call out the network and TLS prerequisites that are commonly missed, and finish with how to handle IdPs that sit behind an additional identity layer. This mechanism works with any OAuth 2.0 (OIDC) identity provider, including Keycloak, Okta, Microsoft Entra ID, PingFederate, and Auth0. OAuth here governs only how Replicator authenticates to your external cluster, so the target can be either Amazon MSK Standard or Express brokers, which always use IAM.

How OAuth authentication works

Before you configure Replicator, it helps to be precise about how the OAuth Kafka handshake works.

The components

  • The Identity Provider (IdP) – Issues access tokens and publishes the public keys. Brokers use these keys to verify the tokens. Examples: Keycloak, Okta, Microsoft Entra ID, PingFederate, Auth0, or a custom OIDC server.
  • The client – In our case, MSK Replicator, acting as a Kafka consumer/producer against your external cluster.
  • The resource server – Your self-managed Kafka broker, which must decide whether to admit a connection.
  • The access token – A JWT (JSON Web Token): a base64url-encoded, three-part string header.payload.signature that the IdP cryptographically signs.

The SASL/OAUTHBEARER handshake, step by step

The following sequence diagram shows the full exchange, from Replicator requesting a token to the broker accepting the connection:

Sequence diagram of the SASL/OAUTHBEARER handshake: Replicator requests a token from the IdP, receives a signed JWT, presents it to the Kafka broker, and the broker verifies the JWT against cached JWKS keys before accepting the connection.

Figure 1: The SASL/OAUTHBEARER handshake. Replicator gets a signed JWT from the IdP and presents it to the broker, which verifies it against cached JWKS keys before accepting the connection.

Walking through it:

  1. Request a token – Replicator asks the IdP for an access token. The exact request depends on the grant type (covered in the next section).
  2. Receive a signed JWT – The IdP returns a signed JWT access token.
  3. Present the token – Replicator opens a SASL/OAUTHBEARER connection to the external Kafka brokers and presents the JWT.
  4. Verify locally – The broker verifies the JWT signature against the IdP’s cached JWKS public keys, without calling the IdP per message.
  5. Connection accepted – The broker admits the connection and derives the Kafka principal from the preferred_username claim.

Step 4 is worth dwelling on: the broker validates the token locally. It fetches the IdP’s JWKS (JSON Web Key Set, the public half of the IdP’s signing keys, RFC 7517) from an endpoint like https://idp.example.com/realms/kafka/protocol/openid-connect/certs and caches it, refreshing on a configurable interval (and re-fetching if it sees a key ID it doesn’t recognize). Incoming JWT signatures are then verified against those cached keys. The IdP is not in the hot path of message traffic. It is contacted only to (a) issue tokens to clients, and (b) serve its public keys for the periodic JWKS refresh.

What the Kafka broker checks

When Replicator presents a JWT, the broker validates:

  • Signature – Proves the IdP issued the token and no one tampered with it (verified against JWKS).
  • iss (issuer) – Must match the broker’s configured oauth.valid.issuer.uri, byte-for-byte, including scheme, host, port, and path. A mismatch is a common configuration error.
  • exp (expiry) – Expired tokens are rejected. Strimzi’s client callback handler proactively refreshes before expiry, so you shouldn’t see mid-stream failures.
  • The principal claim – Typically preferred_username. The broker uses this as the Kafka principal in ACLs (for example, User:service-account-msk-replicator). This matters: the identity Replicator authenticates as on the external cluster must have ACLs that you configure to grant it the read/describe permissions it needs.

Mapping your IdP to a Replicator grant type

A grant type is the protocol by which the client proves its identity to the IdP and obtains a token. This is the front half of the preceding handshake (steps 1 and 2). MSK Replicator supports three of them. You already know how your Kafka clients authenticate to your IdP today, so start from that.

Which grant to use?

Find the row that matches how your clients get tokens today:

How your Kafka clients get tokens from the IdP today Grant type Long-lived secret? What you trust/register on the IdP
A client_id / client_secret (confidential client) CLIENT_CREDENTIALS Yes (stored on AWS Secrets Manager) Nothing new: reuse the existing client, or create one for Replicator
You want secretless, and your IdP can trust an external token issuer IAM_JWT_BEARER No AWS STS as an external token (OIDC) issuer. Trust its JWKS
You want secretless, and your IdP models workloads as signed-JWT clients CLIENT_CREDENTIALS_ASSERTION No AWS STS as the client’s signing authority (private_key_jwt). Trust its JWKS

The simplest mapping is like-for-like: if your clients use a client_id/client_secret, point Replicator at the same client with CLIENT_CREDENTIALS. If you’d rather not give Replicator a long-lived secret, the two secretless grants let it authenticate with its AWS identity instead. Choose between them based on how your IdP prefers to trust an external party.

The rest of this section explains why the three grants differ, using an analogy. If your row is clear and you only want the configuration, skip ahead to Configuring and creating the replicator.

A scenario: checking in at a secure office building

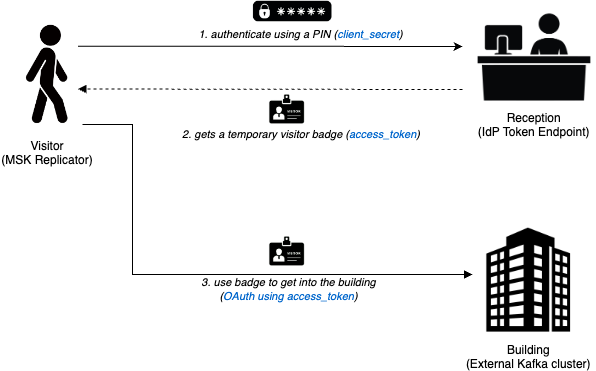
A visitor needs to get into a secure office building. They can’t walk straight in. First they stop at the reception desk to prove who they are and collect a temporary access pass. Only then can they use that pass at the building’s turnstile to get inside. In OAuth terms: the building is your external Kafka cluster, the reception desk is the IdP, the temporary access pass is the access token (JWT), and the visitor is MSK Replicator. Presenting the pass at the turnstile is the SASL/OAUTHBEARER step, and it works the same way for every grant type. What differs is how the visitor proves who they are at the reception desk before it prints a pass.

Scenario 1: CLIENT_CREDENTIALS (the shared PIN)

CLIENT_CREDENTIALS scenario shown as a visitor entering a building: the visitor authenticates at reception with a PIN (the client secret), receives a temporary badge (the access token), and uses it to enter the building (the Kafka cluster).

Figure 2: CLIENT_CREDENTIALS. The visitor authenticates at reception with a PIN (the client_secret), gets a temporary badge (the access token), and uses it to enter the building (the Kafka cluster).

At the reception desk the visitor keys in a PIN the desk already have on file (the client_secret), collects a temporary access pass in return (the access token), and uses that pass to get into the building. Both sides hold the same secret. In practice (RFC 6749 §4.4), Replicator authenticates to the IdP with a client_id/client_secret stored on AWS Secrets Manager, receives the access token, and presents it to the external Kafka brokers over SASL/OAUTHBEARER. Use it when your IdP already issues client secrets for machine clients. This is usually a like-for-like move that reuses the client your existing producers and consumers use, or a new one created for Replicator.

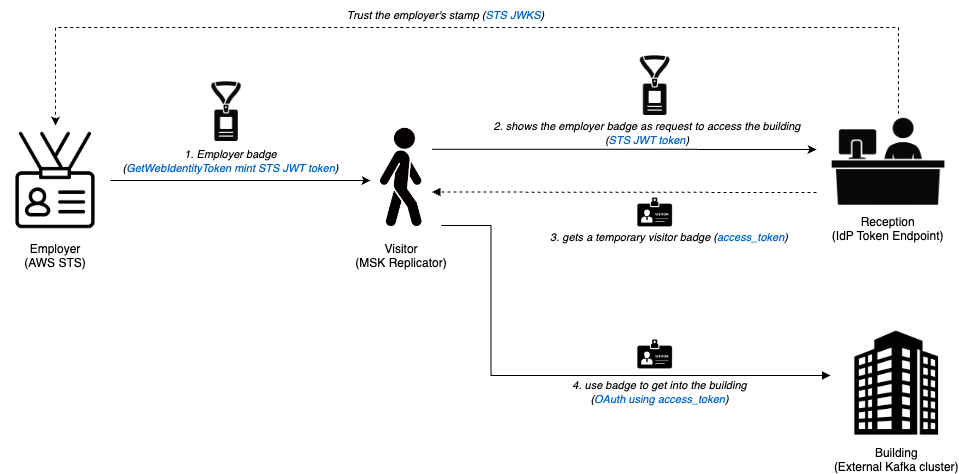
Scenario 2: IAM_JWT_BEARER (the badge is the request)

IAM_JWT_BEARER scenario: the visitor presents an employer-signed badge (an STS JWT) to reception as the request itself and receives an access token, because reception trusts the employer’s stamp (the STS JWKS).

Figure 3: IAM_JWT_BEARER. The visitor shows an employer-signed badge (an STS JWT) to reception as the request itself and gets an access token. Reception accepts it because it trusts the employer’s stamp (the STS JWKS).

First, the visitor collects an employer-signed badge: Replicator calls STS GetWebIdentityToken to mint an STS JWT. At the reception desk the badge itself is the request. The visitor shows it to ask for a pass. Reception trusts the employer’s tamper-proof stamp (STS JWKS), so it accepts the badge and prints a temporary access pass. In practice (RFC 7523 §2.1), the STS JWT is sent as the authorization grant (assertion), and the IdP trusts AWS STS as an external token issuer. Use it when you want secretless authentication, and your IdP can trust an external issuer’s JWTs.

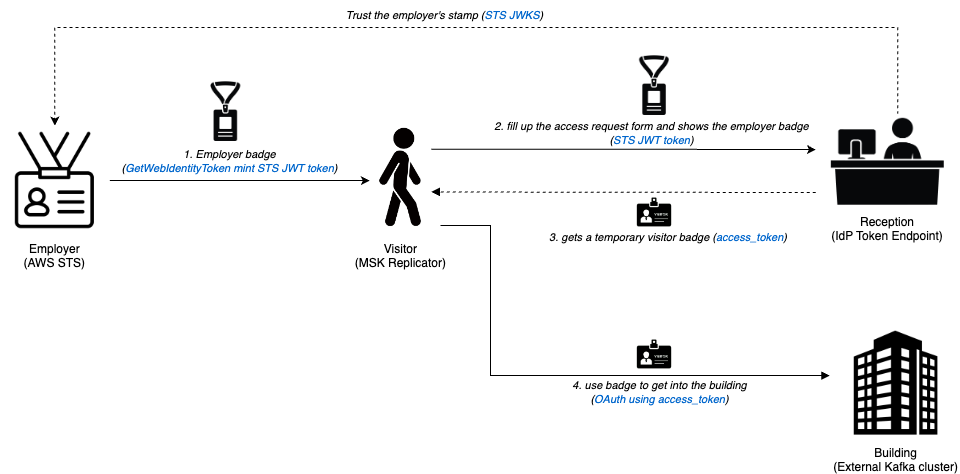
Scenario 3: CLIENT_CREDENTIALS_ASSERTION (the same badge, used as ID on the form)

CLIENT_CREDENTIALS_ASSERTION scenario: the visitor fills out reception’s standard request form and attaches the same STS JWT as identification to receive an access token, which reception grants by trusting the employer’s stamp (the STS JWKS).

Figure 4: CLIENT_CREDENTIALS_ASSERTION. The visitor fills out reception’s standard request form and attaches the same STS JWT as ID, getting an access token. Reception trusts the employer’s stamp (the STS JWKS).

The visitor again collects the same employer-signed badge (STS JWT). This time they fill out the reception desk’s standard access request form (the client_credentials grant) and attach the badge to it as identification, all in one submission. Reception trusts the same employer stamp (STS JWKS) and prints a temporary access pass. In practice (RFC 7521/RFC 7523 §2.2), the same STS JWT is sent as the client_assertion on the client_credentials grant, with the IdP trusting STS as the client’s signing authority (private_key_jwt). Use it when you want secretless authentication and your IdP models external workloads as signed-JWT clients.

Scenarios 2 and 3 in one sentence. Both mint the same STS JWT and share the same benefit: nothing shared can leak, because there is no secret. They differ only in where the STS JWT sits in the token request. IAM_JWT_BEARER sends it as the assertion (the badge is the request), while CLIENT_CREDENTIALS_ASSERTION sends it as the client_assertion on a standard client_credentials request (the badge is ID on the form). That single difference is what you register on the IdP: AWS STS as an external token issuer, or as the client’s signing authority.

Solution overview

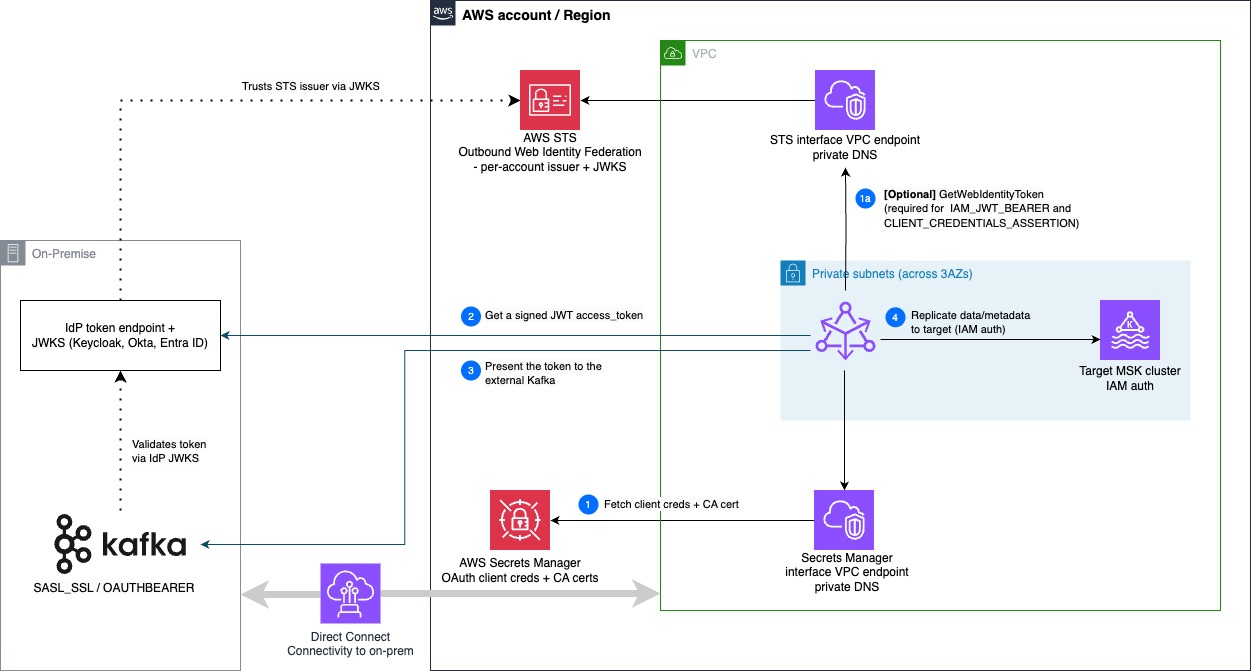
Now that you can map your setup to a grant type, the next question is where these pieces actually run. MSK Replicator runs on AWS managed infrastructure but attaches elastic network interfaces (ENIs) into the subnets of the target Amazon MSK cluster’s virtual private cloud (VPC) and initiates every connection from there under a Service Execution Role (SER). Those ENIs sit in private subnets that typically have no NAT or internet gateway, so each external dependency needs an explicit network path. The following diagram shows the full topology for an OAuth migration, including the two pieces that are commonly missed: STS Outbound Web Identity Federation (for the secretless grants) and the interface VPC endpoints for STS and Secrets Manager.

Deployment architecture: the source environment holds the IdP and Kafka brokers; the AWS account holds STS, Secrets Manager, and the Amazon MSK VPC, whose private subnets contain the Replicator ENIs and target cluster, reached through interface VPC endpoints.

Figure 5: Deployment architecture. The source environment holds the IdP and Kafka brokers. The AWS account holds STS, Secrets Manager, and the Amazon MSK VPC, whose private subnets contain the Replicator ENIs and target cluster, reached through interface VPC endpoints.

The source environment (on the left, shown as on-premises here, but it can equally be another cloud or a self-managed cluster on AWS) holds two components: the IdP token endpoint and JWKS (Keycloak, Okta, Entra ID) and the external Kafka brokers on a SASL_SSL / OAUTHBEARER listener. Everything else runs in your AWS account.

The two dotted lines are trust relationships you configure ahead of time, not runtime calls:

  • External Kafka validates token by using IdP JWKS – The broker checks every presented access token against the IdP’s published public keys. This applies to all grants.
  • IdP trusts STS issuer through JWKS – For the secretless grants only, the IdP is configured to trust your account’s STS issuer and validate the STS-signed JWT against STS’s JWKS. When STS Outbound Web Identity Federation is enabled, AWS provisions a per-account issuer URL (https://<id>.tokens.sts.global.api.aws) whose JWKS the IdP trusts. This trust is not used by CLIENT_CREDENTIALS.

The numbered arrows are the runtime flow, all originating from the Replicator ENIs:

  • Step 1: Fetch client credentials and the CA certificate from AWS Secrets Manager, through its VPC endpoint. For CLIENT_CREDENTIALS this includes the client_id/client_secret. For the secretless grants it is only the CA certificate(s).
  • Step 1a (optional): Call GetWebIdentityToken on AWS STS, through the STS VPC endpoint, to mint a JWT of Replicator’s AWS identity. Required only for IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION.
  • Step 2: Get a signed JWT access token from the IdP token endpoint, exchanging either the client secret or the STS JWT depending on the grant.
  • Step 3: Present the token to the external Kafka brokers over SASL/OAUTHBEARER.
  • Step 4: Replicate to the target Amazon MSK cluster using IAM authentication.

The two supporting pieces inside the VPC, the Secrets Manager and STS interface VPC endpoints, are commonly overlooked precisely because the private subnets have no NAT or internet gateway. We cover exactly why they’re needed, and when, in the following section, Cross-cutting requirements.

Configuring and creating the replicator

With the architecture in mind, you can now configure Replicator itself. MSK Replicator models OAuth through a saslOAuthBearer structure on the external cluster’s clientAuthentication. Exactly one of three mechanism members must be present: clientCredentials, iamJwtBearer, or clientCredentialsAssertion. The control plane enforces this mutual exclusivity. Fields shared across all three (tokenEndpointUrl, scope, tokenEndpointAuthenticationMethod, tokenEndpointTlsCertificateArn, and saslExtensions) live at the saslOAuthBearer level.

Before the per-grant details, here are the requirements that apply to every OAuth migration, whichever grant you choose. Most OAuth setup failures trace back to one of these, so review them first.

Cross-cutting requirements

Here are the five items that apply to every grant: TLS trust, secret format, network reachability, the Service Execution Role, and STS federation.

a) TLS everywhere, and two separate trust settings

Replicator connects to two TLS endpoints, and they are configured independently:

  • encryptionInTransit.rootCaCertificate: the CA that signed your Kafka brokers’ TLS certificates (the SASL_SSL listener – :9096).
  • tokenEndpointTlsCertificateArn: the CA that signed your IdP’s token endpoint TLS certificate (for example – Keycloak on :8443).

If your broker and IdP are signed by the same private CA, you still must supply the CA in both fields. Omitting tokenEndpointTlsCertificateArn when the IdP uses a private or self-signed cert produces a PKIX path building failed error during token acquisition. Because that fails before workers stabilize, you’ll see a generic failure with no worker logs. If your IdP uses a publicly-trusted certificate (for example, it sits behind a public endpoint), you can omit tokenEndpointTlsCertificateArn entirely.

b) Secret format: store key/value pairs, not raw values

Every secret Replicator reads (client credentials, CA certificate) is parsed by the config provider as a set of key/value pairs. Use the Secrets Manager console’s Key/value editor rather than pasting raw text, and it will serialize and escape the values for you.

The keys the provider expects:

Key Value Used for
certificate the CA in PEM (newlines escaped as \n) CA-certificate secrets (rootCaCertificate, tokenEndpointTlsCertificateArn)
client_id, client_secret your OAuth client credentials the CLIENT_CREDENTIALS token-request secret

Custom parameters, headers, and SASL extensions. Some IdPs require extra data on the token request, and some brokers require SASL/OAUTHBEARER extensions. The config provider supports both through reserved key prefixes in the same secret:

Prefix Effect Example key Example value
custom_param. adds a parameter to the token request sent to the IdP custom_param.tenant_token myTenantToken
custom_header. adds an HTTP header to the IdP token request custom_header.X-Tenant-Id acme
extension. adds a SASL/OAUTHBEARER extension presented to the broker (for example, Confluent Cloud’s logicalCluster) extension.logicalCluster myLogicalClusterId

For example, an IdP that expects a tenant token as a request parameter and a Confluent Cloud broker that requires a logical-cluster extension would add custom_param.tenant_token and extension.logicalCluster as extra key/value pairs alongside client_id/client_secret in the same secret.

c) Network reachability from Replicator’s ENIs

Replicator attaches ENIs into the subnets you specify (through the target amazonMskCluster cluster’s vpcConfig) and initiates all connections from there. Those ENIs must be able to reach:

  1. Your external brokers, over VPC peering, AWS Transit Gateway, AWS Direct Connect, or VPN, with security groups permitting the SASL_SSL port.
  2. Your IdP’s token endpoint, over the same networking. The endpoint hostname must resolve from those subnets.
  3. AWS Secrets Manager, to fetch credentials/CA. If the subnets have no NAT/internet gateway, add an interface VPC endpoint for com.amazonaws.<region>.secretsmanager with private DNS.
  4. AWS STS (only for IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION), to call GetWebIdentityToken. In no-egress subnets this will time out (STS GetWebIdentityToken call failed: Connect timed out) unless you add an interface VPC endpoint for com.amazonaws.<region>.sts with private DNS. This is the most common oversight for the secretless grants.

Both endpoints use private DNS, so the standard secretsmanager.<region>.amazonaws.com and sts.<region>.amazonaws.com hostnames resolve to the endpoint inside the VPC, with no client change needed.

A note on vpcConfig placement. For an external Apache Kafka cluster, vpcConfig is specified on the target amazonMskCluster entry, not the external apacheKafkaCluster entry. The API rejects a vpcConfig on the external cluster. The ENIs it creates are what reach both clusters and all AWS endpoints.

d) The Service Execution Role (SER)

Replicator assumes an IAM role to do its work. Two parts matter:

  • Trust policy – Must allow the Replicator service to assume it. kafka.amazonaws.com needs to be trusted. A trust policy that is too narrow fails with AccessDenied.ServiceExecutionRoleUnassumable.
  • Permissions – The replication permissions are extensive and depend on which features you enable, so follow the service execution role permissions reference to build a least-privilege policy.

e) Enabling STS Outbound Web Identity Federation (secretless grants only)

For IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION, sts:GetWebIdentityToken must be enabled for your account/role. When enabled, AWS provisions a dedicated issuer URL of the form https://<uuid>.tokens.sts.global.api.aws. Every JWT STS mints for your account carries this as its iss claim, and its public keys are published under this issuer’s JWKS. You configure your IdP to trust this issuer. Granting the sts:GetWebIdentityToken IAM action is necessary but not sufficient. The account-level federation feature must also be turned on.

Create the replicator

A repeatable way to create the replicator is with a request file and --cli-input-json, so you can keep the full configuration under version control. The following example is a complete CLIENT_CREDENTIALS request. The two secretless variants change only the saslOAuthBearer block (shown after).

aws kafka create-replicator \
  --region <region> \
  --cli-input-json file://create-replicator.json

create-replicator.json:

{
  "replicatorName": "oauth-migration-replicator",
  "serviceExecutionRoleArn": "arn:aws:iam::<acct>:role/msk-replicator-execution-role",
  "kafkaClusters": [
    {
      "apacheKafkaCluster": {
        "apacheKafkaClusterId": "<source-cluster-id>",
        "bootstrapBrokerString": "b-1.ext-kafka.example.com:9096,b-2.ext-kafka.example.com:9096"
      },
      "clientAuthentication": {
        "saslOAuthBearer": {
          "tokenEndpointUrl": "https://idp.example.com/realms/kafka/protocol/openid-connect/token",
          "clientCredentials": {
            "tokenRequestSecretArn": "arn:aws:secretsmanager:<region>:<acct>:secret:<oauth-creds>"
          },
          "tokenEndpointAuthenticationMethod": "POST",
          "tokenEndpointTlsCertificateArn": "arn:aws:secretsmanager:<region>:<acct>:secret:<idp-ca>"
        }
      },
      "encryptionInTransit": {
        "encryptionType": "TLS",
        "rootCaCertificate": "arn:aws:secretsmanager:<region>:<acct>:secret:<broker-ca>"
      }
    },
    {
      "amazonMskCluster": {
        "mskClusterArn": "arn:aws:kafka:<region>:<acct>:cluster/target-msk/<uuid>"
      },
      "vpcConfig": {
        "subnetIds": [
          "subnet-aaaa",
          "subnet-bbbb",
          "subnet-cccc"
        ],
        "securityGroupIds": [
          "sg-xxxxxxxx"
        ]
      }
    }
  ],
  "replicationInfoList": [
    {
      "sourceKafkaClusterId": "<source-cluster-id>",
      "targetKafkaClusterArn": "arn:aws:kafka:<region>:<acct>:cluster/target-msk/<uuid>",
      "targetCompressionType": "NONE",
      "topicReplication": {
        "topicsToReplicate": [
          ".*"
        ],
        "detectAndCopyNewTopics": true,
        "copyTopicConfigurations": true
      },
      "consumerGroupReplication": {
        "consumerGroupsToReplicate": [
          ".*"
        ],
        "detectAndCopyNewConsumerGroups": true,
        "synchroniseConsumerGroupOffsets": true
      }
    }
  ]
}

Field names and exact nesting follow the create-replicator API reference. Check it for the full schema and any Region-specific values.

The example above uses CLIENT_CREDENTIALS. For the full schema, any Region-specific values, and detailed examples for the other grant types, check the MSK documentation.

With the requirements and configuration in hand, here is the order to put them in:

  1. Pick your grant type using the preceding decision table. CLIENT_CREDENTIALS is the fastest path if you already manage a client secret. Otherwise choose a secretless grant based on how your IdP models external workloads. For a multi-hop internal chain, use IAM_JWT_BEARER against the proxy pattern described in the next section.
  2. Prepare the IdP: create the client (or the STS-trust configuration), and note the exact token endpoint URL and issuer.
  3. Stage secrets in Secrets Manager, as JSON (requirement b): client credentials (if any) and the CA certificate(s).
  4. Wire the network (requirement c): connectivity from Replicator’s subnets to your brokers and IdP, plus interface VPC endpoints for Secrets Manager and (secretless grants only) STS, both with private DNS.
  5. [Optional but recommended]: Smoke-test the path from inside the VPC – IdP setup is often the part that takes the most iterations, and Replicator provisioning is a slow way to discover a misconfigured token endpoint or a missing TLS trust. Spin up a small EC2 instance in Replicator’s subnets, install a Kafka client, and run an end-to-end produce/consume against the external brokers using SASL/OAUTHBEARER (a client_credentials flow is simplest). This validates the three things most likely to be wrong (network reachability to the IdP and brokers, both TLS trusts for the broker CA and IdP CA, and token vending) while you can still fix them in seconds. Tear the instance down once the round trip works.
  6. Enable STS Outbound Web Identity Federation (requirement e. Secretless grants only) and configure your IdP to trust the resulting issuer.
  7. Build the SER (requirement d) with a trust policy the Replicator service can assume and the required permissions.
  8. Create the replicator with the create-replicator request for your grant. Remember both TLS trust fields for a private-CA IdP (requirement a), and vpcConfig on the target entry only.
  9. Verify – Produce to a topic on the external cluster and confirm the records land on the target (consume with IAM auth on the Amazon MSK side). Then watch the health signals:
    • In the Amazon MSK console, the replicator should reach the RUNNING state.
    • In Amazon CloudWatch, under the AWS/Kafka namespace, watch the replicator’s ReplicationLatency and MessageLag metrics. Both should be low and stable, and MessageLag should trend toward zero as it catches up.
    • A healthy replicator commits offsets continuously. A steady “1 message per batch” with no producer activity is only the internal heartbeat topic, not a stall.

Handling an additional identity layer: the federation-proxy pattern

Who owns what – Before the details, the ownership line is simple and worth stating up front:

  • What Replicator guarantees: it calls the configured tokenEndpointUrl with the configured grant, includes the STS JWT, expects a standard {access_token, token_type, expires_in} response, and refreshes before expiry.
  • What you own: everything at and behind the proxy, including validating the STS JWT, the downstream token exchanges, claim mapping, and the availability and latency of the endpoint. The proxy runs in your VPC and is owned entirely by you.

So far we have assumed you can point Replicator at a single token endpoint. Some organizations can’t. Instead, they have an internal identity chain: several hops of token exchange and federation that a workload must traverse before it holds a token the Kafka brokers accept.

A representative example is a large financial institution whose chain has several hops: an AWS workload’s identity (a signed GetCallerIdentity request) is exchanged at an internal Token Exchange service for an intermediate JWT, which an internal IdP then consumes as a client_assertion to issue the final Bearer token the Kafka brokers accept.

Replicator connects to a single HTTPS token endpoint using one of the three grant types and expects a standard token response. When the identity flow spans multiple hops like this, you place a proxy in front of that chain so Replicator still sees a single endpoint.

The solution: a customer-owned proxy

You deploy a small proxy in your own VPC that collapses the chain behind a single endpoint. From Replicator’s perspective, this is an ordinary OAuth flow against one token endpoint. Everything behind that endpoint is opaque to Replicator and owned entirely by you.

The grant Replicator uses to reach the proxy is a separate choice from the exchanges happening behind it. We recommend a secretless grant (IAM_JWT_BEARER or CLIENT_CREDENTIALS_ASSERTION) so there is no long-lived secret between Replicator and the proxy. CLIENT_CREDENTIALS is also valid if you would rather the proxy authenticate Replicator with a client secret. The following walkthrough uses IAM_JWT_BEARER, where the proxy validates the STS JWT that Replicator presents.

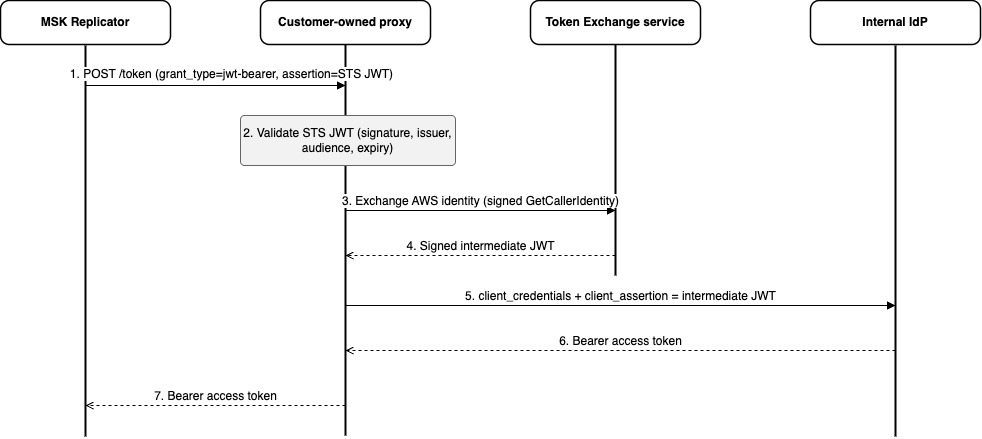
How it works, end to end. The following sequence diagram traces the full token exchange, from Replicator’s request to the Bearer it finally presents to the external Kafka brokers.

Federation-proxy token flow: the proxy validates Replicator’s STS JWT, exchanges its own AWS identity at the Token Exchange service for an intermediate JWT, presents that to the internal IdP, and returns the resulting Bearer token to Replicator.

Figure 6: Federation-proxy token flow. The proxy validates Replicator’s STS JWT, exchanges its own AWS identity at the Token Exchange service for an intermediate JWT, presents that to the internal IdP, and returns the resulting Bearer to Replicator.

  1. Replicator to proxy – Replicator POSTs its STS JWT as assertion to the proxy’s token endpoint, a plain IAM_JWT_BEARER request (grant_type=jwt-bearer). Because the endpoint is private, Replicator reaches it through an execute-api interface VPC endpoint, the same private-connectivity approach used for Secrets Manager and STS. (Replicator first obtains the STS JWT by calling STS GetWebIdentityToken through the STS VPC endpoint.)
  2. Proxy validates the STS JWT (signature against STS’s JWKS, plus iss/aud/exp/sub checks. The sub is the caller’s AWS ARN).
  3. Proxy to Token Exchange service – The proxy exchanges its own AWS identity, presented as a signed GetCallerIdentity request, at the internal Token Exchange service.
  4. Token Exchange service → proxy – It returns a signed intermediate JWT.
  5. Proxy to internal IdP – The proxy makes a client_credentials request that carries the intermediate JWT as the client_assertion.
  6. Internal IdP to proxy – The IdP issues the final Bearer access token.
  7. Proxy to Replicator – The proxy returns the Bearer, and Replicator presents it to the external brokers over SASL/OAUTHBEARER. The brokers validate it against the final IdP’s JWKS, a completely ordinary OAuth handshake from their point of view.

Reference architecture

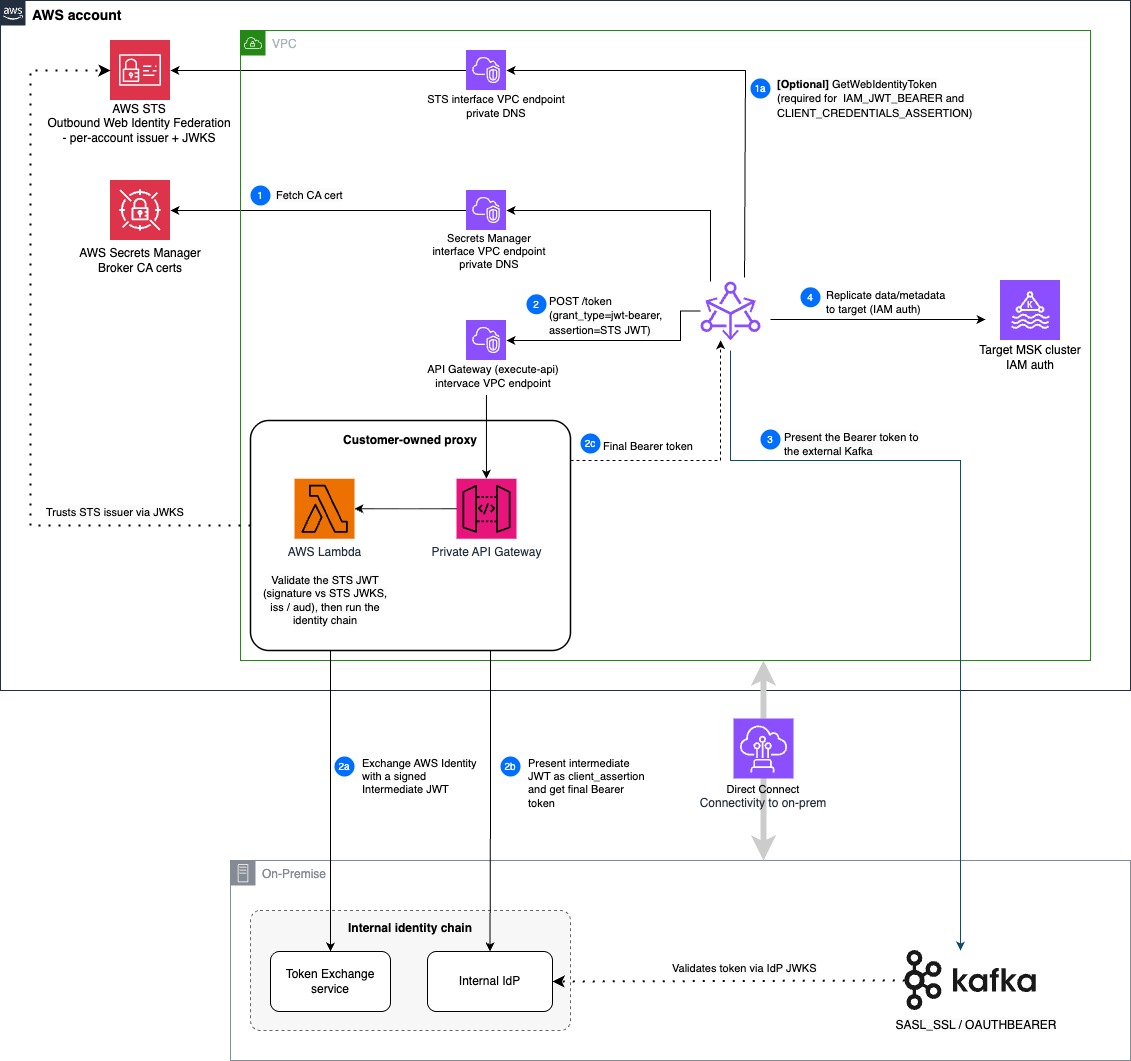
Here is the reference architecture for the end-to-end solution.

Federation-proxy reference architecture: Replicator ENIs in a private subnet call a customer-owned proxy (a Lambda function behind a private API Gateway) that runs the on-premises identity chain over Direct Connect before Replicator replicates into the target Amazon MSK cluster.

Figure 7: Federation-proxy reference architecture. Replicator ENIs in a private subnet call a customer-owned proxy (a Lambda behind a private API Gateway), which runs the on-premises identity chain over Direct Connect before Replicator replicates into the target Amazon MSK cluster.

Everything on the Replicator side runs in your VPC’s private subnets: the Replicator ENIs, the customer-owned proxy, and the target Amazon MSK cluster. The proxy here is an AWS Lambda function behind a private Amazon API Gateway, but it can run on any compute you prefer (EC2, ECS, or EKS) as long as it exposes a single private HTTPS token endpoint. Connectivity to the on-premises Token Exchange service, internal IdP, and Kafka brokers runs over AWS Direct Connect (a VPN or VPC peering works too).

The outer legs of this flow are exactly the base migration from Solution overview: step 1 (fetch the broker CA from Secrets Manager), step 1a (mint the STS JWT through STS), step 3 (present the Bearer to the brokers), and step 4 (replicate to the target with IAM). What’s new here is the proxy hop in the middle, which replaces the single “step 2” call to a token endpoint:

  • 2. POST /token – Replicator sends the STS JWT as the assertion to the proxy’s private token endpoint, reached through the execute-api interface VPC endpoint. The proxy validates it against STS’s JWKS.
  • 2a. Exchange AWS identity – The proxy presents its own AWS identity (a signed GetCallerIdentity request) to the internal Token Exchange service and gets back a signed intermediate JWT.
  • 2b. Present as client_assertion The proxy sends a client_credentials request to the internal IdP with the intermediate JWT as the client_assertion, and receives the final Bearer.
  • 2c. Final Bearer token – The proxy returns the Bearer to Replicator, which then continues at step 3.

As in the base architecture, the dotted lines are prerequisite trust relationships, not runtime calls: the proxy trusts AWS STS as an issuer (validating the STS JWT against STS’s JWKS), and the Kafka brokers validate the final Bearer against the internal IdP’s JWKS.

One subtlety worth calling out is the split of TLS trust. Replicator connects directly only to the private API Gateway (which uses a publicly trusted certificate) and to the Kafka brokers, so the only certificate it fetches from Secrets Manager is the broker CA. The internal IdP’s CA is the proxy’s concern: the proxy terminates TLS to the Token Exchange service and internal IdP, so it carries their CA material, not Replicator.

The same single-endpoint pattern handles other “extra layer” scenarios without any Replicator change: claim enrichment (the proxy intercepts and augments), rate-limited IdPs (the proxy caches tokens), IdPs requiring mTLS (the proxy terminates Replicator’s HTTPS and initiates mTLS onward), and IdP migrations (swap the proxy’s target without touching Replicator config).

A working reference implementation of this customer-owned proxy is available at GitHub.

Conclusion

In this post, we walked through how to migrate a self-managed, OAuth-authenticated Apache Kafka cluster to Amazon MSK using MSK Replicator: how the SASL/OAUTHBEARER handshake works, how to map your identity provider to one of the three supported grant types, the deployment architecture and prerequisites that the connection depends on, and how to handle identity providers that sit behind an additional federation layer. To get started, see the Amazon MSK Developer Guide and the Amazon MSK Replicator documentation. For the federation-proxy example, see the sample implementation on GitHub.


About the author

Subham Rakshit

Subham Rakshit

Subham is a Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughters.

Announcing in-place ZooKeeper-to-KRaft cluster upgrades for Amazon MSK

Post Syndicated from Austin Groeneveld original https://aws.amazon.com/blogs/big-data/announcing-in-place-zookeeper-to-kraft-cluster-upgrades-for-amazon-msk/

Apache Kafka 4.0 officially removes ZooKeeper. If your Amazon Managed Streaming for Apache Kafka (Amazon MSK) Provisioned clusters still run in ZooKeeper metadata mode, now is the time to plan your migration. Amazon MSK now supports in-place upgrades from ZooKeeper to KRaft metadata mode, so you can modernize your existing cluster’s metadata management through the familiar version upgrade workflow.

For more than a decade, Apache ZooKeeper provided dependable metadata management for Kafka, including controller election, partition state, broker registration, and topic configuration. With Apache Kafka 4.0, ZooKeeper is officially removed in favor of KRaft, an embedded Raft-based consensus protocol that handles metadata management internally. It brings those responsibilities into Apache Kafka itself, creating a more streamlined foundation for the continued evolution of Kafka. Amazon MSK has supported KRaft-mode clusters since May 2024, and all Kafka 4.x versions on Amazon MSK use KRaft.

With the in-place upgrade, you can retain your cluster data and metadata while Amazon MSK manages the control-plane transition. Your cluster remains available for produce and consume traffic throughout the process, with no expected downtime if you’re following best practices. By using the existing version upgrade workflow, the move to KRaft becomes a natural step in your cluster’s lifecycle. This prepares your cluster for Kafka 4.x and future Kafka releases.

Prerequisites

Before initiating the upgrade, review the following requirements to confirm your cluster is ready for the transition.

Supported source versions

Clusters must be running Kafka 3.9.x in ZooKeeper mode to use the in-place upgrade. If your cluster is running an earlier version, such as 3.6.0, 3.7.x, or 3.8.x, first complete a standard in-place version upgrade to 3.9.x. You can then initiate the upgrade to 3.9.x.kraft.

Kafka 3.9 is the bridge release for this transition because it supports both ZooKeeper and KRaft modes. To support customers through this migration process, Amazon MSK provides extended support for 3.9.x for a minimum of 2 years from its April 2025 release.

Client compatibility

Requirement Detail
Minimum client library Apache Kafka client v3.0+
Recommended client version v3.9 or above
Connection strings Must use bootstrap.servers only. Any ZooKeeper connection strings (the --zookeeper flag) must be removed before upgrade.

The --zookeeper admin flag was deprecated in Kafka 2.5 and removed in 3.0. Before upgrading, update any remaining applications or tools that connect directly to ZooKeeper.

Pre-upgrade checklist

Before beginning the upgrade, confirm the following:

  • For Standard brokers, the cluster must be deployed across three Availability Zones. Express brokers provide this by default.
  • The cluster is running Kafka 3.9.x in ZooKeeper mode.
  • Standard brokers expose direct ZooKeeper access on ports 2181 (plaintext) and 2182 (TLS). Before upgrading, validate that you’ve disabled ZooKeeper access on the cluster and none of your applications rely on these connections.
  • Solutions using dynamic Kafka configurations that relied on ZooKeeper have been removed before attempting the upgrade operation.
    • If you previously configured custom domain names on a ZooKeeper-based deployment using the dynamic override (kafka-configs.sh --alter on advertised.listeners), be aware that KRaft does not support this dynamic configuration. If you attempt to upgrade your MSK cluster to KRaft with altered advertised.listeners, the upgrade operation fails.
    • If you’re implementing your custom domain name solution on MSK moving forward with KRaft, we recommend our coinciding MSK release for custom domain name support by statically configuring the custom.advertised.listeners property through the UpdateClusterConfiguration API.
  • The cluster has no under-replicated partitions.
  • The cluster is running within per-broker partition limits for standard or express broker clusters.
  • For clusters running above the KRaft brokers-per-cluster limit, you might need an additional quota increase. If you previously raised a quota increase for your ZooKeeper brokers-per-cluster, submit another quota increase for the KRaft limit before attempting the upgrade.
  • The cluster has enough reserve capacity to support rolling broker restarts while serving client traffic.
  • As a best practice, verify that monitoring is ready for the transition from ZooKeeper-specific metrics to KRaft controller metrics.
    • After the migration, ZooKeeper-specific Amazon CloudWatch metrics such as ZookeeperRequestLatencyMsMean and ZookeeperSessionState are no longer available.
    • If you use Open Monitoring, Kafka also stops publishing ZooKeeper metrics. Plan to update or retire related alerts and dashboards as part of your migration preparation.

How the upgrade works

When you initiate the upgrade, Amazon MSK performs a managed, multi-phase migration:

  1. Controller quorum bootstrap: Amazon MSK provisions KRaft controller nodes alongside the existing ZooKeeper infrastructure. Both systems operate in parallel during this phase.
  2. Metadata migration: The KRaft controller reads the cluster state from ZooKeeper and writes it to the internal KRaft metadata log.
  3. Broker transition: Amazon MSK performs a rolling update and registers with the KRaft controller quorum. Data plane operations remain available during the transition.
  4. Validation and bake period: Amazon MSK verifies cluster health under KRaft, including partition leadership, replication state, and controller responsiveness.
  5. ZooKeeper decommissioning: After validation succeeds, Amazon MSK removes the ZooKeeper infrastructure and the cluster operates entirely in KRaft mode.

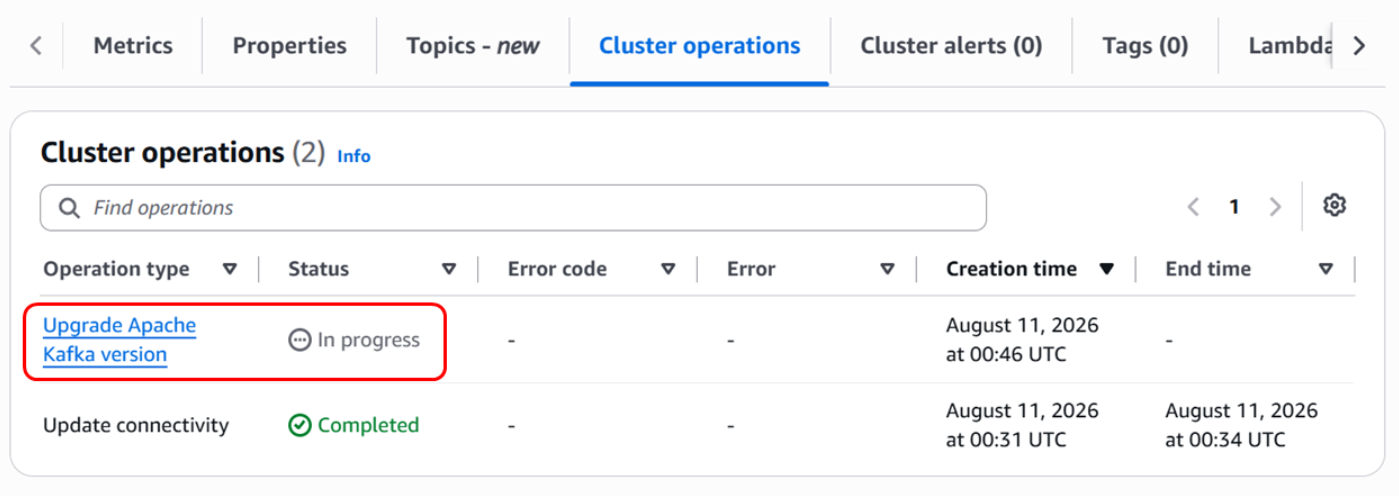
During the upgrade, the cluster enters UPDATING state. You can continue producing and consuming data, while Amazon MSK administrative API operations are temporarily unavailable until the cluster returns to ACTIVE.

Amazon MSK maintains a high bar for durability during the transition. It uses rigorous safety checks at each phase of the migration to protect customer metadata in both roll-forward and rollback scenarios.

Built-in recovery

Amazon MSK monitors cluster health throughout the upgrade. If it detects a condition that prevents the migration from completing, it automatically returns the cluster to its pre-migration state. No customer action is required during recovery.

The operation status changes to Reverting to pre-migration state while Amazon MSK restores the original Kafka version and reconnects ZooKeeper. After the cluster returns to ACTIVE, the describe-cluster-operation API provides error codes, failure reasons, and recommended remediation steps. You can use these to address the issue before starting the upgrade again.

How to perform the upgrade

The following steps walk you through the upgrade process using the Amazon MSK console. You can also perform these steps programmatically using the AWS Command Line Interface (AWS CLI) or SDK.

Step 1: Disable ZooKeeper access (standard brokers only)

Note: This step applies only to Standard broker clusters. Express broker clusters don’t expose direct ZooKeeper access and can skip directly to Step 2.

Standard brokers expose direct ZooKeeper access on ports 2181 (plaintext) and 2182 (TLS). Before upgrading, validate that none of your applications rely on these connections.

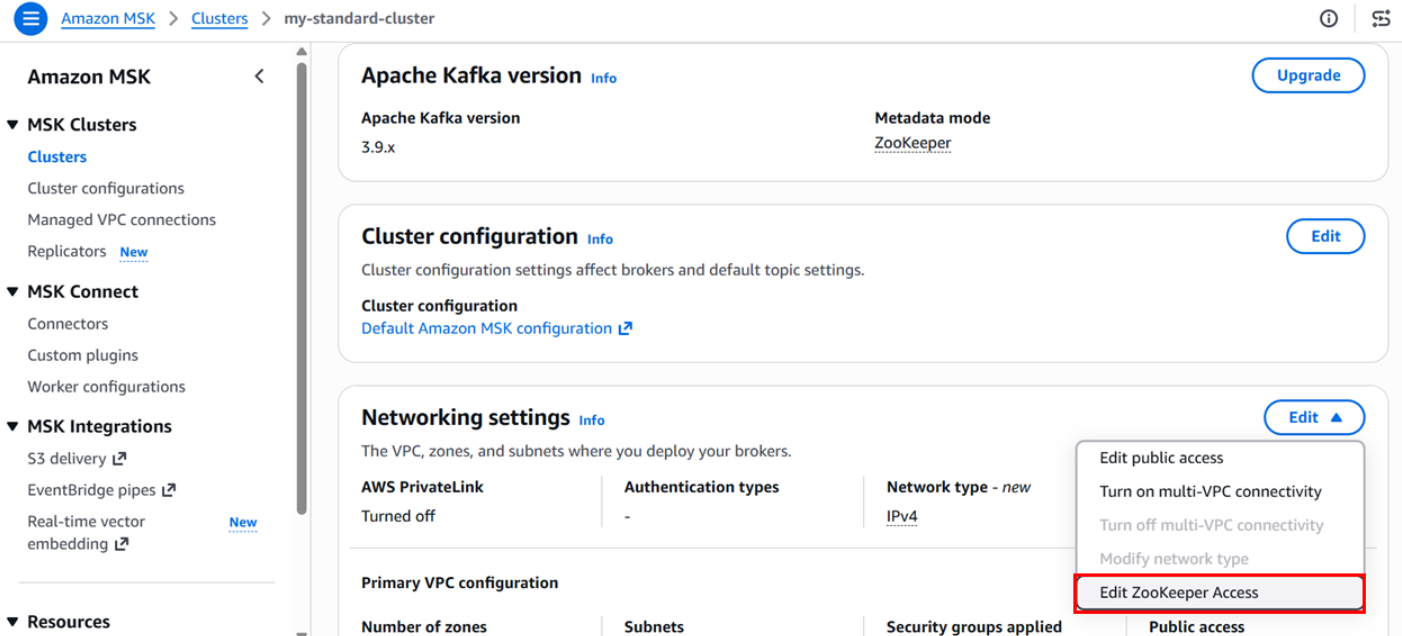
Navigate to your cluster’s Properties tab, choose Network settings, and then choose Edit ZooKeeper access.

Figure 1: Editing ZooKeeper access from the cluster network settings

Figure 1: Editing ZooKeeper access from the cluster network settings

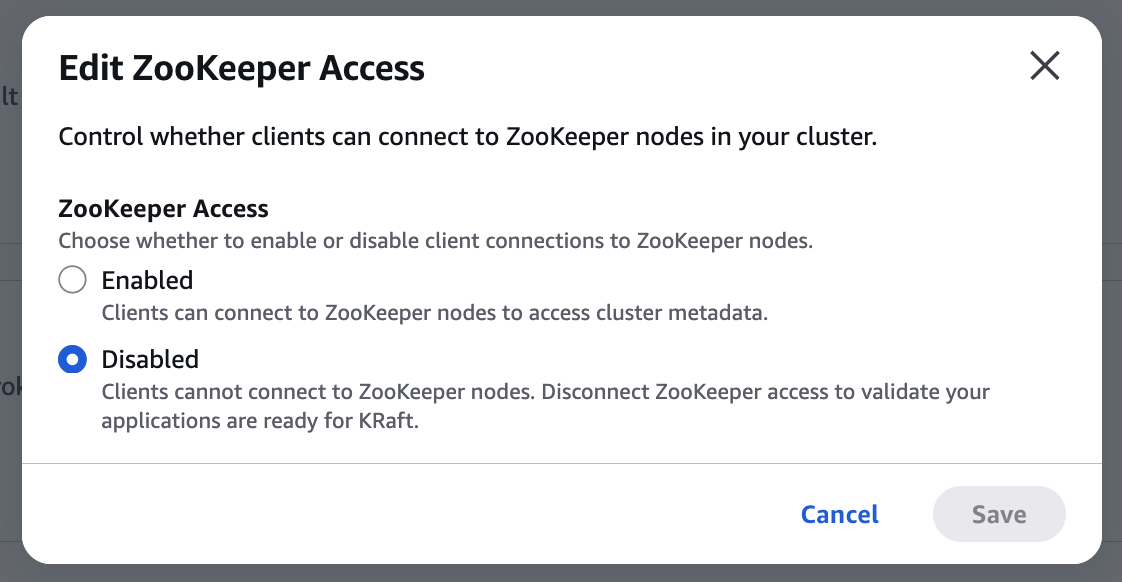
In the pop-up window, verify that ZooKeeper access is set to Disabled, and then choose Save.

Edit ZooKeeper access dialog with access set to Disabled and the Save button

Figure 2: Confirming ZooKeeper access is disabled

Confirm that producers, consumers, and admin tooling continue operating normally without ZooKeeper connectivity. This step is fully reversible. Re-enable ZooKeeper access immediately if anything breaks.

Figure 3: Verifying client traffic continues without ZooKeeper access

Step 2: Initiate the version upgrade

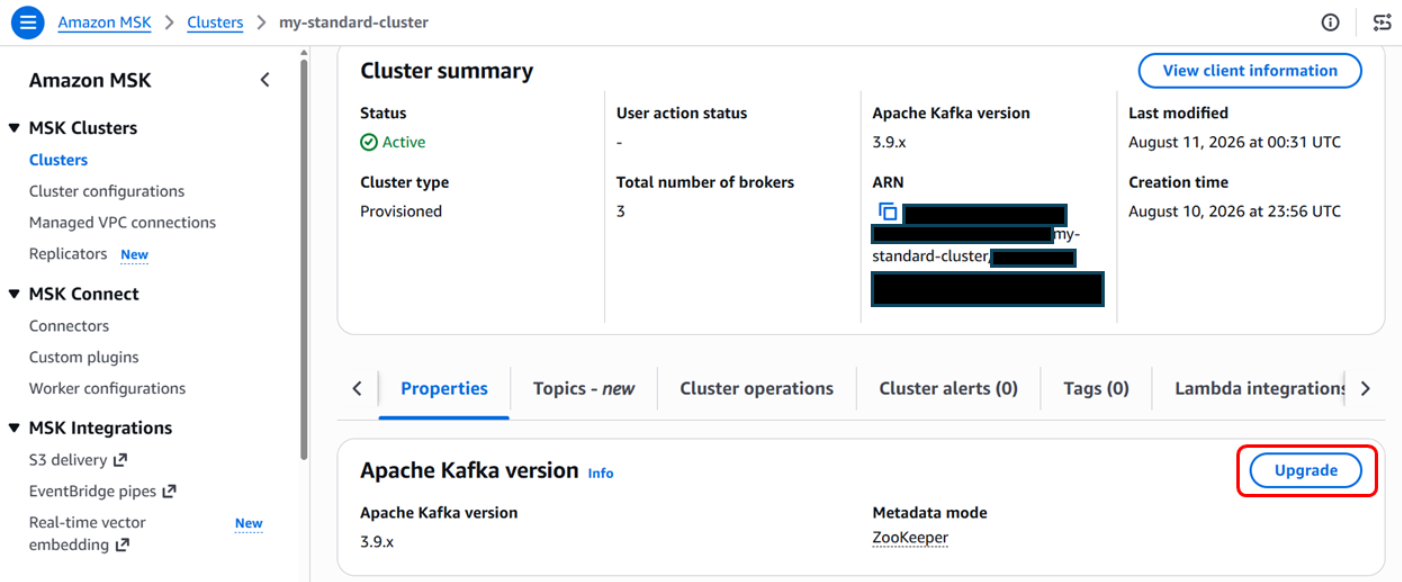
In the Amazon MSK console, under Properties, choose Upgrade in the Apache Kafka version section.

Figure 4: Starting a version upgrade from the Apache Kafka version section

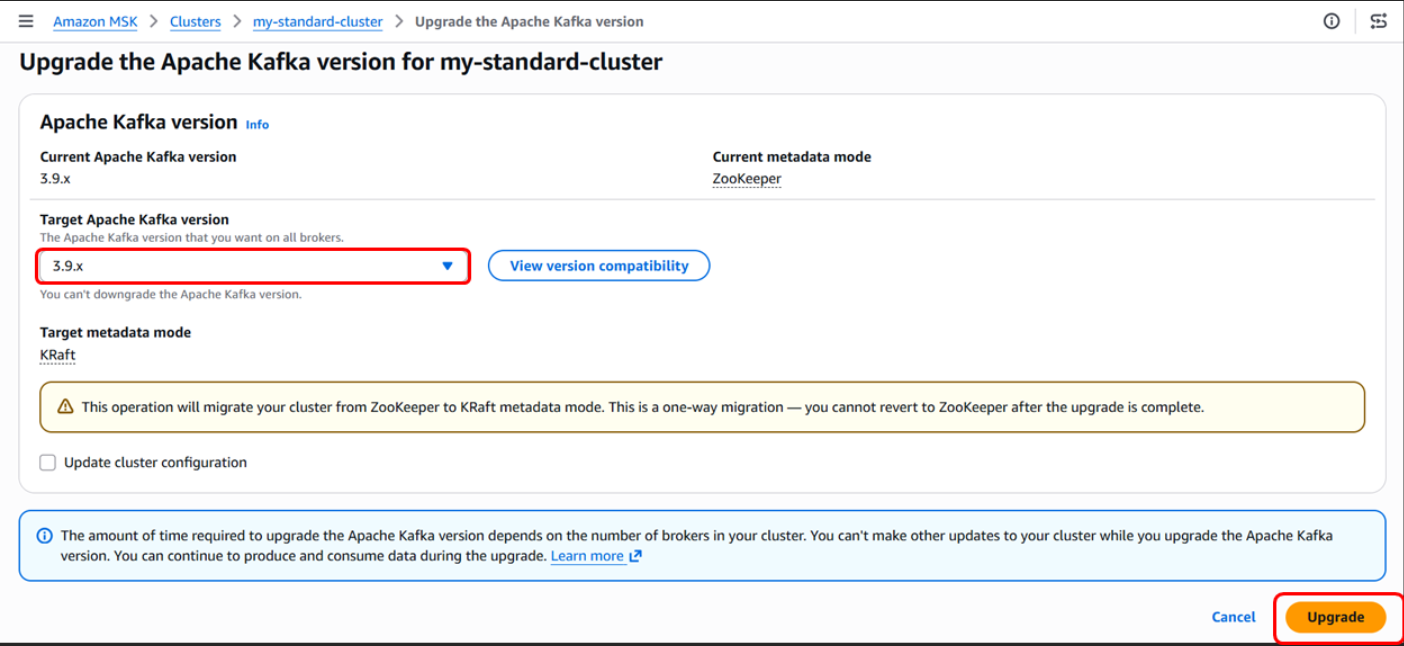
Select your cluster and start a version upgrade to 3.9.x with Target metadata mode set to KRaft. Choose Upgrade.

Figure 5: Selecting KRaft as the target metadata mode

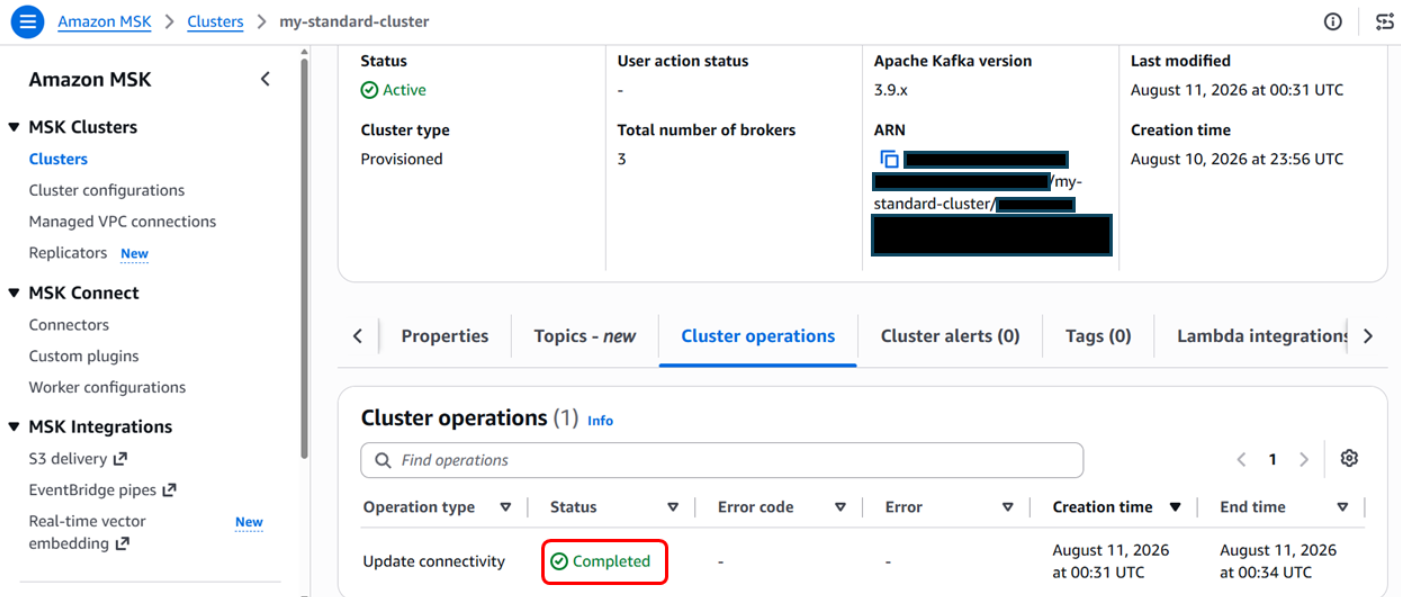
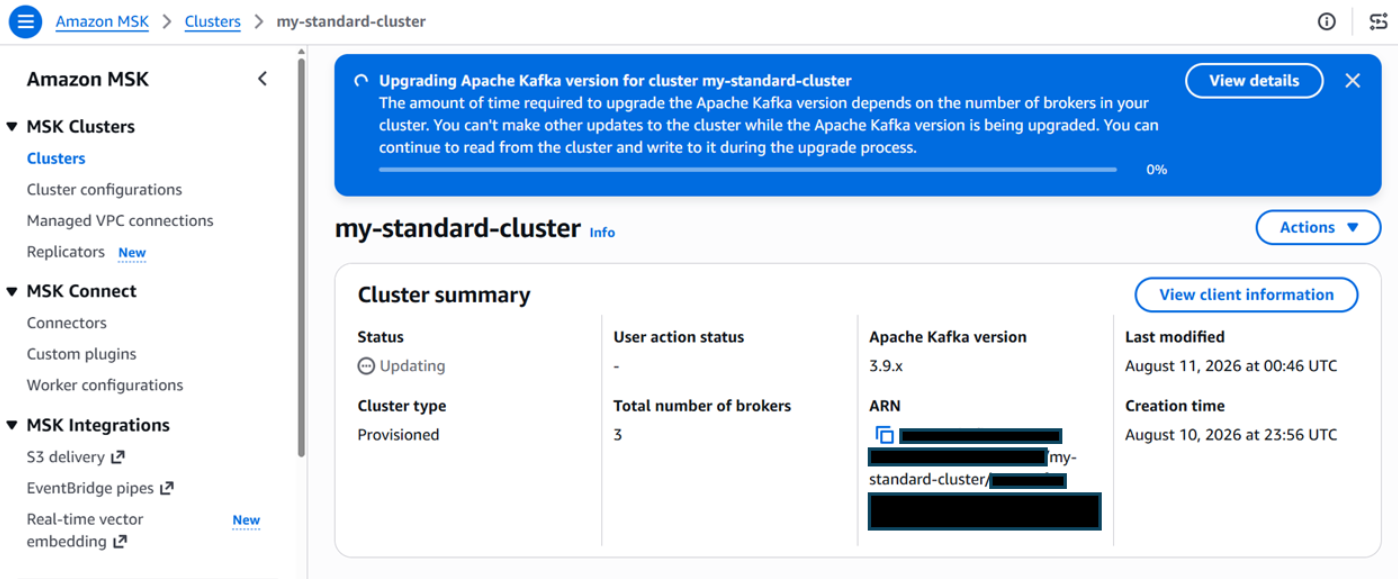
You can monitor your upgrade progress on the cluster properties page.

Figure 6: Monitoring upgrade progress on the cluster properties page

Step 3: Monitor upgrade progress

Track progress on the Cluster operations tab in the Amazon MSK console or with the describe-cluster-operation API.

Figure 7: Tracking the upgrade on the Cluster operations tab

Step 4: Validate the KRaft cluster

After the cluster returns to ACTIVE state in KRaft mode:

  • Verify that topics, partitions, and consumer groups are present.
  • Confirm producer and consumer throughput aligns with pre-migration baselines.
  • Update or disable any ZooKeeper-specific monitoring alerts.
  • Update operational documentation and runbooks to reflect KRaft mode.

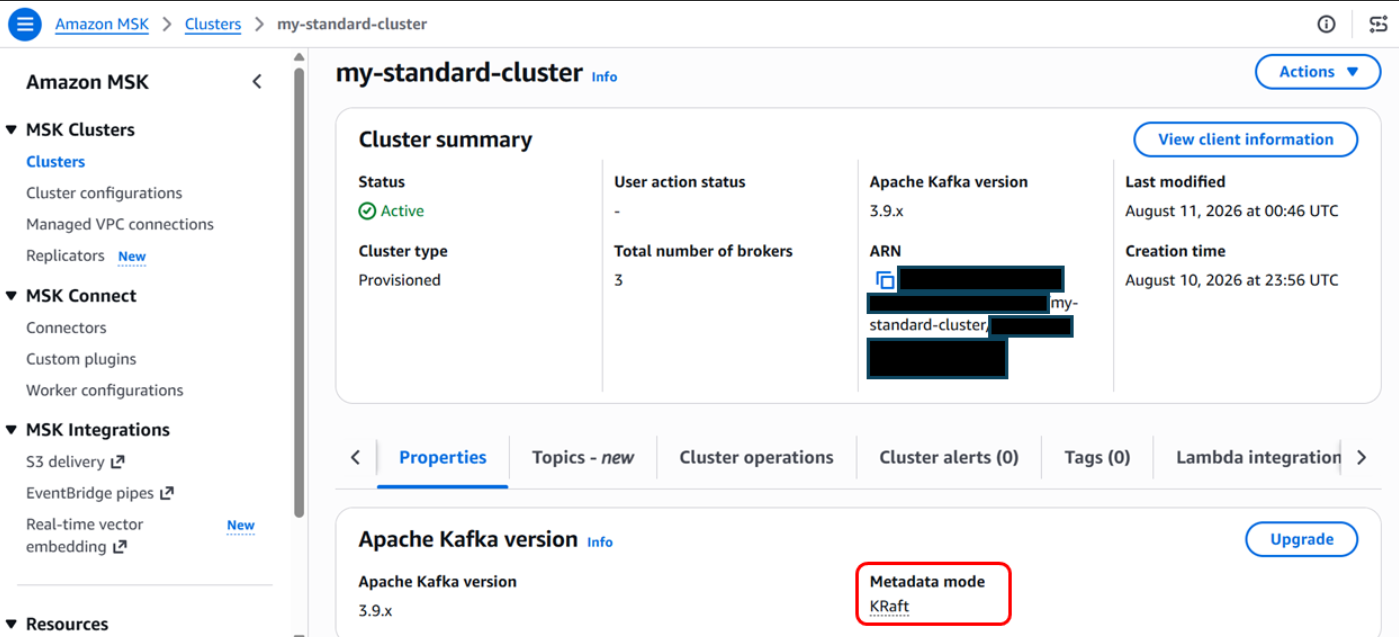
Figure 8: Cluster running in KRaft mode after the upgrade

After the upgrade completes, your cluster appears in an Active state with KRaft enabled as the metadata mode.

Get ready for the next generation of Kafka on Amazon MSK

The in-place ZooKeeper-to-KRaft mode upgrade makes it straightforward to prepare existing Amazon MSK clusters for the future of Apache Kafka. Beyond removing external metadata dependencies, KRaft delivers faster failover times and higher partition limits per cluster. Amazon MSK handles the entire metadata transition, rolling broker updates, validation, and recovery workflow for you. With the new in-place experience, you have a clear, streamlined path to upgrade on your schedule and unlock enhanced scalability and resilience.

For more details, see the Amazon MSK Developer Guide and the supported Kafka versions documentation.


About the authors

Austin Groeneveld

Austin Groeneveld

Austin is a Streaming Specialist Solutions Architect at Amazon Web Services (AWS), based in the San Francisco Bay Area. In this role, Austin is passionate about helping customers accelerate insights from their data using the AWS platform. He is particularly fascinated by the growing role that data streaming plays in driving innovation in the data analytics space. Outside of his work at AWS, Austin enjoys watching and playing soccer, traveling, and spending quality time with his family.

Ashley Millette

Ashley Millette

Ashley is a Specialist Solutions Architect for Streaming and Analytics at AWS. She partners with customers to design and implement real-time data streaming architectures using services like Amazon MSK, helping them build scalable, cost-effective pipelines that turn data in motion into actionable insights. She is passionate about simplifying complex streaming workloads and enabling customers to modernize their data infrastructure with confidence.

Detecting multi-stage attacks on AWS: A guide to cross-service signal correlation

Post Syndicated from Nisha Kashyap original https://aws.amazon.com/blogs/security/detecting-multi-stage-attacks-on-aws-a-guide-to-cross-service-signal-correlation/

A single alert from one security service tells you something happened. Read that signal alongside activity from other services and your own business context, and you will know whether what happened is part of a multi-stage attack.

Consider a short sequence. An identity calls GetCallerIdentity from a source address it hasn’t previously used. Within minutes, that same identity runs a burst of List and Describe calls across several services, and some of them fail with AccessDenied. Soon after, a large volume of data leaves your environment toward a domain that was registered last week. Amazon GuardDuty might already flag pieces of this, such as the reconnaissance from an unfamiliar source, through finding types like Recon:IAMUser/* or Discovery:S3/*. What you gain from correlating the pieces yourself is a single view of the sequence, tied to your own business context, so you can act on the whole rather than triaging findings one at a time.

This post is for security engineers and security operations teams who run Amazon Web Services (AWS) detection services and want to catch patterns specific to their environment. You will see how AWS detection and your business context fit together, and how to build correlations that use that context. The examples run in Amazon CloudWatch Logs Insights so you can try them today, and the closing section describes how to grow them into an automated pipeline. The walkthrough later in this post lists the prerequisites for these queries.

Start with AWS detection services

Begin with the AWS detection services. They cover the threats common across customers, and everything in this post is built on them.

Turn these on and tune them before you build anything custom. Tuning means adjusting sensitivity to reduce false positives for your environment, choosing which data sources each service monitors, and suppressing findings for known-good patterns.

GuardDuty correlates multi-stage attacks for you

Before you build anything by hand, see what GuardDuty already does for you. Amazon GuardDuty Extended Threat Detection correlates signals across multiple data sources including AWS CloudTrail, Amazon S3 data events, runtime monitoring, Amazon Elastic Kubernetes Service (Amazon EKS) audit logs, and more, then raises a single critical severity attack sequence finding when it spots a multi-stage pattern. It recognizes sequences such as credential compromise followed by data exfiltration, maps them to MITRE ATT&CK tactics, and attaches a timeline and remediation guidance. If you have GuardDuty enabled today, then GuardDuty Extended Threat Detection is already enabled by default and needs no queries from you. For details on how GuardDuty charges apply, see Amazon GuardDuty pricing.

The credential compromise sequence in the opening example is the kind of universal pattern GuardDuty Extended Threat Detection is built to catch, so rely on it for those. Attack sequence findings show up in the GuardDuty console next to your other findings, and they route to Security Hub and your response workflows the same way.

GuardDuty handles the threats that look the same in every account. What it doesn’t have is the context that makes a given action suspicious in your account. That’s what you provide.

Add your business context

Business context is what only you know about your environment: which buckets hold sensitive data, which principals have a reason to touch which resources, which role chains your policy permits, and when your production change windows open. GuardDuty Extended Threat Detection learns from patterns common across customers, but it can’t answer these environment-specific questions. Express them as correlations and you add a detection layer tuned to your environment. Each of the following four patterns turns one of these facts into a query.

Run these queries in the AWS Management Console for CloudWatch by choosing Logs, then Logs Insights, using the CloudWatch Logs Insights query language. Most read CloudTrail events from a CloudWatch Logs log group that your trail delivers to. If your trail writes only to Amazon S3, add CloudWatch Logs delivery on the trail, or run equivalent queries in Amazon Athena (a serverless query service for analyzing data in Amazon S3 using SQL).

Note: The queries and code in this post use placeholder values. Replace them with your own before running: your-sensitive-bucket (your S3 bucket name), your-key-id (your AWS KMS key ID), region (your AWS Region, such as us-east-1), account-id (your 12-digit AWS account ID), and aws-cloudtrail-logs-my-trail (your CloudTrail log group name).

A note on multi-account environments. In AWS Organizations, an organization trail delivers every account’s events to one log group, so these queries work as-is but return cross-account results. Filter by recipientAccountId for account-scoped views. Without an organization trail, run queries per account or use Amazon Security Lake as a central query surface.

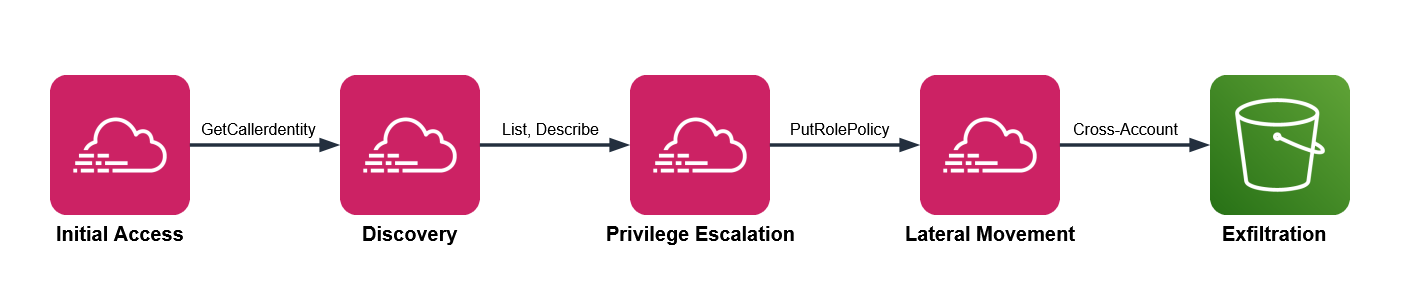
The attack chain mapped to AWS services

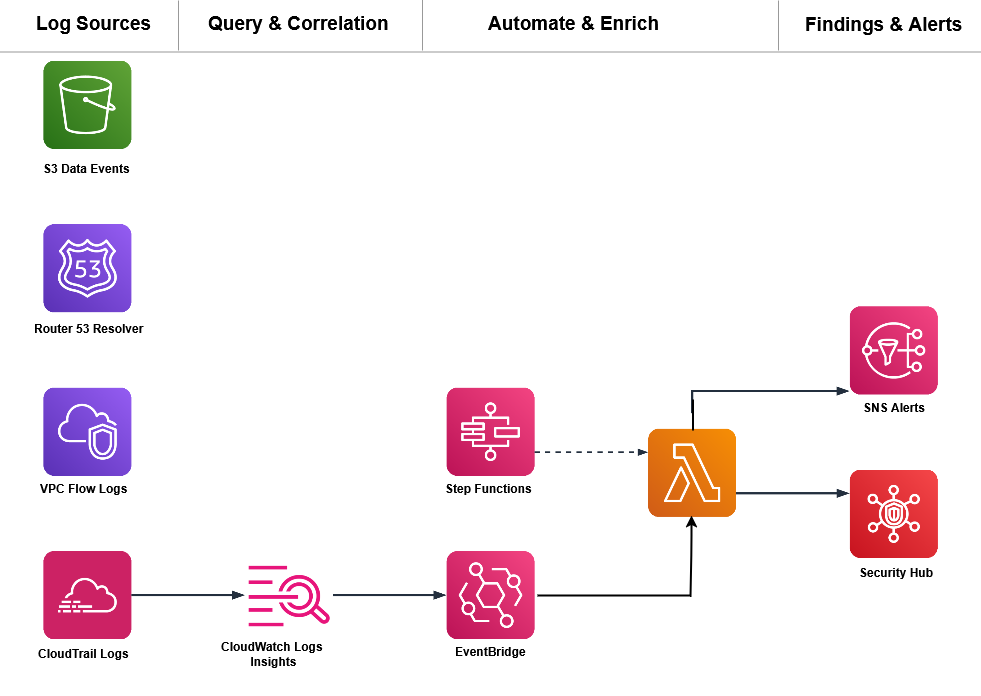
Multi-stage attacks move through five phases, and each phase leaves a signal in a different service. These signals surface across three log sources: CloudTrail, which records API activity in your account; Amazon VPC Flow Logs, which capture network connection metadata; and Amazon Route 53 Resolver query logs, which record DNS queries from your VPCs.

  • Initial access – Stolen credentials reach your environment. CloudTrail records GetCallerIdentity, GetSessionToken, or AssumeRole from an unfamiliar source.
  • Discovery – The threat actor enumerates with List, Describe, and Get calls, often triggering AccessDenied responses.
  • Privilege escalation – The threat actor chains roles or edits policies. CloudTrail records AssumeRole sequences, PutRolePolicy, or CreateAccessKey.
  • Lateral movement – The threat actor moves across accounts or AWS Regions, assuming roles and creating resources in unfamiliar places.
  • Exfiltration – Data leaves through GetObject calls at scale, large outbound transfers in VPC Flow Logs, and DNS queries in Route 53 Resolver query logs to recently registered domains.

Figure 1 shows the five attack phases mapped to the AWS log source that records each one.

Figure 1: Attack chain mapped to AWS services

Figure 1: Attack chain mapped to AWS services

GuardDuty Extended Threat Detection watches this chain for universal patterns. The four patterns that follow add the dimension you supply: your business context.

Pattern one: Sensitive data access by an unexpected principal

Your data classification and access norms drive this detection. One bucket holds customer records, another holds public web assets, and you know which principals have a reason to read the customer records, which are sensitive. Encode that knowledge and an ordinary looking read turns into something worth chasing.

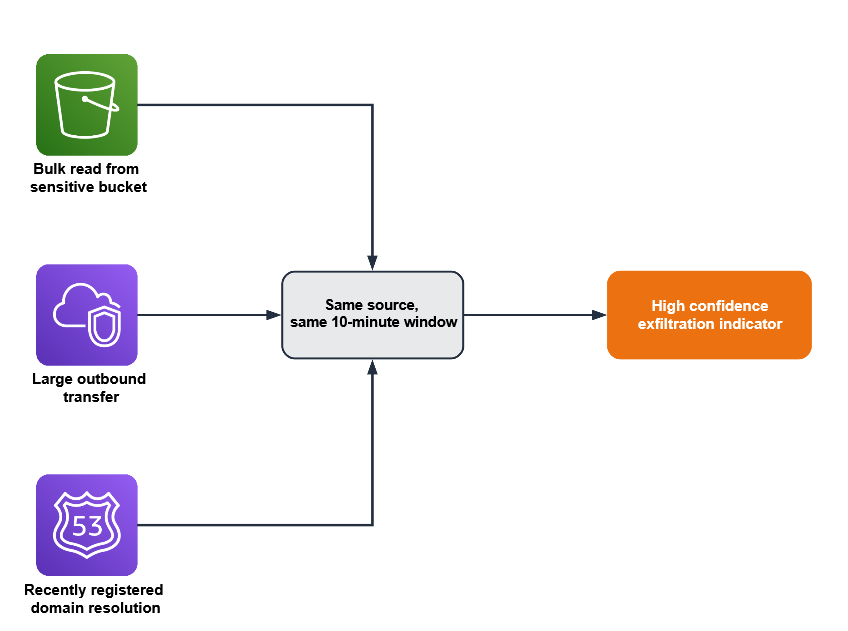
Three signals converge here. CloudTrail shows GetObject at volume on a bucket you’ve classified as sensitive. The principal isn’t on your list of expected readers for that bucket. And VPC Flow Logs show a large outbound transfer from the same source in the same window, while DNS query logs show a recently registered destination domain, which together increase your confidence that there’s a potential threat.

CloudTrail management events don’t record GetObject. You must turn on CloudTrail data events for the buckets you care about to capture GetObject. Many teams miss GetObject because data events weren’t enabled on the relevant buckets.

This query shows bulk reads on a sensitive bucket, grouped by principal. Run it in CloudWatch Logs Insights with your CloudTrail log group selected.

fields @timestamp, userIdentity.arn, requestParameters.bucketName
| filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
| filter requestParameters.bucketName = "your-sensitive-bucket"
| stats count(*) as objectReads,
        count_distinct(requestParameters.key) as distinctObjects
        by userIdentity.arn, bin(10m)
| filter objectReads > 100
| sort objectReads desc

The threshold of 100 is a placeholder. Run the query over a week of normal activity, find the ninety-fifth percentile read count for that bucket, and set the threshold above it. Then check each principal the query returns against your expected reader list. A principal that isn’t on the list, reading at volume, is the result to investigate.

To corroborate, look for a matching outbound transfer. Switch the log group selector to your VPC Flow Logs log group and run this.

fields @timestamp, srcAddr, dstAddr, bytes
| filter action = "ACCEPT"
# exclude RFC 1918 private ranges so only external destinations remain
| filter dstAddr not like /^10\./
        and dstAddr not like /^192\.168\./
        and dstAddr not like /^172\.(1[6-9]|2[0-9]|3[0-1])\./
| stats sum(bytes) as totalBytes by srcAddr, dstAddr, bin(10m)
| filter totalBytes > 1000000000
| sort totalBytes desc

The Amazon S3 query returns a principal, and the Flow Logs query works on IP addresses, so you translate one into the other. The worked example later in this post covers that translation in full.

Picture an analytics role that reads a reporting bucket all day. One afternoon, it reads a thousand objects from your customer records bucket instead. GuardDuty stays quiet, because an authenticated role making valid GetObject calls isn’t suspicious anywhere else. Your query flags it, because that role isn’t on the expected reader list for that bucket. The classification you applied is what turns silence into a signal.

Figure 2 shows a bulk read from a sensitive bucket in CloudTrail, a large outbound transfer in VPC Flow Logs, and a young domain resolution in Route 53 Resolver logs.

Figure 2: Three signals converging within a single time window to indicate exfiltration

Figure 2: Three signals converging within a single time window to indicate exfiltration

Pattern two: A role chain that crosses your access policy

Picture a deployment that assumes one role to build, then a second to release. For one principal, that two-hop AssumeRole chain is routine; for a different principal it’s a policy violation. This pattern relies on your trust topology—the chains your organization permits—so put that knowledge in the query.

This pattern needs three conditions:

  • CloudTrail shows several AssumeRole calls from the same source inside a short window
  • The chain ends in a sensitive action such as CreateAccessKey, PutRolePolicy, or AttachUserPolicy
  • The starting identity isn’t one your policy expects to run that chain

In CloudWatch Logs Insights, select your CloudTrail log group and run this query, which surfaces chains of two or more hops.

fields @timestamp, userIdentity.arn, requestParameters.roleArn, sourceIPAddress
| filter eventName = "AssumeRole"
| stats count(*) as assumeCount,
        count_distinct(requestParameters.roleArn) as rolesAssumed
        by sourceIPAddress, bin(5m)
| filter assumeCount >= 2 and rolesAssumed >= 2
| sort assumeCount desc

Two hops is the minimum for a chain; raise the count if your environment chains roles often. Your deployment pipeline probably assumes several roles an hour, as do AWS service principals such as AWS Security Hub. Exclude the identities you expect to see assuming multiple roles, including your pipeline role and known AWS service principals. What’s left is the set to investigate, such as a person assuming several roles at an odd hour and ending in a new access key. Treat that distinction as data: list the identities and actions you consider normal, and review the chains that fall outside the list.

Pattern three: An encryption key used outside its owning workload

Resource ownership is the signal here. A given AWS Key Management Service (AWS KMS) key creates and controls the encryption keys for a workload, and a single key should serve a single workload, such as a payments service. A Decrypt call against it is a valid, authorized API action, so nothing about the call itself looks wrong. The ownership rule you set is what makes another principal’s use of the key worth a second look.

This pattern applies only to customer-managed keys scoped to one workload. It doesn’t apply to AWS-managed keys (alias/aws/*) or to customer-managed keys intentionally shared across services. Confirm single-workload intent from the key policy’s Principal block before deploying this rule.

Two conditions indicate misuse:

  • CloudTrail shows Decrypt or GenerateDataKey calls on a key that’s tied to one workload
  • The calling principal isn’t the role that owns that workload

Against your CloudTrail log group, run this query to list the principals that called a specific key.

fields @timestamp, userIdentity.arn, eventName
| filter eventSource = "kms.amazonaws.com"
| filter eventName in ["Decrypt", "GenerateDataKey", "Encrypt"]
| filter resources.0.ARN = "arn:aws:kms:region:account-id:key/your-key-id"
| stats count(*) as keyUses by userIdentity.arn, eventName
| sort keyUses desc

Compare what comes back against the one workload role you expect. A principal you don’t recognize on that key is the signal. Because key misuse is an early move in data theft, this correlation catches activity that only your ownership knowledge can flag.

Consider a key that wraps your payments database. The payments service role calls it in normal operation, and nothing else should. If a developer role or a freshly created role runs Decrypt against it, the call succeeds and reads as ordinary in isolation. The reason it matters is the ownership rule you hold in your head and now state in this query.

Pattern four: A privileged action outside your change window

Start with the query, then read what it means.

fields @timestamp, userIdentity.arn, eventName, sourceIPAddress
| filter eventName in ["PutRolePolicy", "AttachRolePolicy",
        "CreateAccessKey", "AuthorizeSecurityGroupIngress", "PutBucketPolicy"]
| stats count(*) as sensitiveChanges by userIdentity.arn, eventName, sourceIPAddress
| sort sensitiveChanges desc

Run it against your CloudTrail log group, scoped to your off-hours window when you schedule it, so it returns only activity outside the change window. Your change process defines what normal looks like here: production security and identity changes flow through a pipeline during defined hours, run by a known actor. A console-driven policy change at 2:00 AM, made by a person rather than the pipeline, doesn’t fit those expectations. The signal is a sensitive change such as PutRolePolicy or AuthorizeSecurityGroupIngress, made outside the window, by a person rather than your pipeline role.

Exclude the actors you expect, such as your deployment pipeline role, your patch automation role, and AWS service principals like AWS CloudFormation and AWS Systems Manager. What remains is privileged change made outside your process, which is both what an attacker does to establish persistence and what your own change discipline says shouldn’t happen.

Your pipeline might open security group rules during a deployment every weekday afternoon. A person opening a security group rule at midnight on a weekend is the same API call carrying a very different meaning. The schedule and the actor, both facts you define, are what separate the two.

Build your first correlation rule

The following walkthrough uses pattern one as a complete example. The other three patterns follow the same design with their own queries.

Prerequisites

These prerequisites feed the queries in this walkthrough. Confirm each one before you start:

  • A CloudTrail trail logging management events to a CloudWatch Logs log group
  • CloudTrail data events enabled for your sensitive S3 buckets
  • GuardDuty enabled, with its protection plans and Extended Threat Detection
  • VPC Flow Logs on for your production VPCs
  • Amazon Route 53 Resolver query logging on

CloudTrail, GuardDuty, VPC Flow Logs, and Route 53 Resolver query logging provide the raw signals that your correlations connect. Without them, the queries in this post return empty results.

Step 1: Record the bucket and its expected readers

Choose one sensitive bucket to monitor, and write down the principals allowed to read it. Store the list where your automation can reach it, such as a configuration file in version control or an Amazon DynamoDB table (a managed NoSQL database).

{
  "customer-records-prod": [
    "arn:aws:iam::123456789012:role/AnalyticsPipeline",
    "arn:aws:iam::123456789012:role/ComplianceAudit"
  ],
  "financial-data-archive": [
    "arn:aws:iam::123456789012:role/FinanceReporting"
  ]
}

This example hardcodes the list for simplicity. In production, load it from a DynamoDB table or Parameter Store so you can update it without redeploying.

Step 2: Baseline before you set a threshold

Run the pattern one query over one week of normal activity. Find the 95th percentile read count for the bucket and use a value greater than that as your alert threshold. This step keeps legitimate high-volume access from generating false positives later.

Set the THRESHOLD_READS environment variable to this value when you configure the function in Step 5.

Step 3: Run the access query

In the CloudWatch console:

  1. Choose Logs, then choose Logs Insights.
  2. In the Select log group(s) dropdown, select your CloudTrail log group.
  3. Set the time range to 3h (the last three hours).
  4. In the query editor, paste the pattern one query.
  5. Replace your-sensitive-bucket with your bucket name.
  6. Choose Run query.
  7. Review the principals in the results table.
  8. Compare each principal against your expected reader list from step 1, and flag any that are not on it.

Each result includes a principal that step 4 translates into an IP address.

Step 4: Correlate with network activity

CloudTrail logs actions by AWS Identity and Access Management (IAM) principal, while VPC Flow Logs record traffic by IP address. To connect the two signals, translate the principal into its address.

For a role attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the userIdentity.principalId field includes the instance ID after the colon, in the form AROAEXAMPLE:i-1234567890abcdef0. Copy the instance ID and look up its private IP address.

aws ec2 describe-instances \
  --instance-ids i-1234567890abcdef0 \
  --query "Reservations[0].Instances[0].PrivateIpAddress" \
  --output text

Other compute types differ. A VPC-connected AWS Lambda function sends traffic through elastic network interfaces in your subnets, so correlate on those interface addresses. An Amazon Elastic Container Service (Amazon ECS) task records its network interface in task metadata. For a plain assumed-role session with no instance behind it, the sourceIPAddress field in CloudTrail already holds the caller’s address, so you correlate on it directly.

Run the Flow Logs query from pattern one, filtering srcAddr to that address within 10 minutes of the Amazon S3 read timestamp. A match places the same source behind both the sensitive read and a large external transfer in one window. CloudTrail events reach CloudWatch Logs 5–15 minutes after the API call, so correlate on eventTime rather than query time. Query a wider lookback than your correlation window: for example, look back 30 to 60 minutes but correlate on a 10-minute eventTime window. Steps 3 and 4 are manual validation; step 5 automates them.

Figure 2 shows DNS resolution as a third corroborating signal. This walkthrough implements the CloudTrail and VPC Flow Logs correlation. To add DNS, apply the same run_query() pattern against your Route 53 Resolver query log group.

Step 5: Automate the check

Move the query into a Lambda function (serverless compute that runs your code without a server to manage), send results to a notification channel, and schedule regular runs. Work through the following sub-procedures.

To create the notification channel

  1. Open the Amazon Simple Notification Service (Amazon SNS) console. Amazon SNS is a managed messaging service that delivers notifications to subscribers.
  2. In the navigation pane, choose Topics.
  3. Choose Create topic.
  4. For Type, select Standard.
  5. For Name, enter security-correlation-alerts.
  6. Choose Create topic.
  7. Note the topic Amazon Resource Name (ARN) at the top of the topic details page. You will use it in the function.
  8. Choose Create subscription.
  9. For Protocol, select Email.
  10. For Endpoint, enter your email address or incident management endpoint.
  11. Choose Create subscription, then confirm the subscription from the email AWS sends.

To create the EventBridge Scheduler execution role

The schedule needs a role that lets it invoke your function, and its trust policy needs conditions that pin the role to the schedule you own. Without those conditions, another account with access to the scheduler service could theoretically call this role; a class of misuse known as the confused deputy problem.

1. Create a trust policy file named scheduler-trust-policy.json.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": { "Service": "scheduler.amazonaws.com" },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringEquals": {
          "aws:SourceAccount": "ACCOUNT-ID"
        },
        "ArnLike": {
          "aws:SourceArn": "arn:aws:scheduler:REGION:ACCOUNT-ID:schedule/*/s3-access-correlation-hourly"
        }
      }
    }
  ]
}

2. Create the role, then attach permission to invoke the function. Scope Resource to the specific function ARN so this role can’t invoke anything else.

aws iam create-role \
  --role-name EventBridgeSchedulerRole \
  --assume-role-policy-document file://scheduler-trust-policy.json

aws iam put-role-policy \
  --role-name EventBridgeSchedulerRole \
  --policy-name LambdaInvokePolicy \
  --policy-document '{
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "Allow",
        "Action": "lambda:InvokeFunction",
        "Resource": "arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction"
      }
    ]
  }'

When you create the function, Lambda automatically creates an execution role. You will attach the permissions this function needs to that role in a later step.

To deploy the correlation function

  1. Open the Lambda console.
  2. Choose Create function.
  3. For Function name, enter CorrelationFunction.
  4. For Runtime, select the latest Python runtime.
  5. Choose Create function.
  6. On the Code tab, replace the default code with the following function, then choose Deploy.
import os
import time
import logging
import boto3
from botocore.exceptions import ClientError

logger = logging.getLogger()
logger.setLevel(logging.INFO)

logs = boto3.client("logs")
sns = boto3.client("sns")
ec2 = boto3.client("ec2")

CLOUDTRAIL_LOG_GROUP = os.environ["CLOUDTRAIL_LOG_GROUP"]
FLOWLOGS_LOG_GROUP = os.environ["FLOWLOGS_LOG_GROUP"]
SNS_TOPIC = os.environ["SNS_TOPIC_ARN"]
BUCKET = os.environ["SENSITIVE_BUCKET"]
THRESHOLD = int(os.environ.get("THRESHOLD_READS", "100"))

# Expected readers per bucket
EXPECTED_READERS = {
    "customer-records-prod": [
        "arn:aws:iam::123456789012:role/AnalyticsPipeline",
        "arn:aws:iam::123456789012:role/ComplianceAudit",
    ],
}


def run_query(log_group, query, start, end):
    """Start a Logs Insights query and wait for it to finish."""
    started = logs.start_query(
        logGroupName=log_group,
        startTime=start,
        endTime=end,
        queryString=query,
    )
    query_id = started["queryId"]
    while True:
        outcome = logs.get_query_results(queryId=query_id)
        if outcome["status"] in ("Complete", "Failed", "Cancelled"):
            break
        time.sleep(1)
    if outcome["status"] != "Complete":
        raise RuntimeError(f"Query did not complete: {outcome['status']}")
    return [{f["field"]: f["value"] for f in row} for row in outcome["results"]]


def private_ip_for_principal(principal_id):
    """Resolve an EC2 instance role principalId to its private IP."""
    if ":" not in principal_id:
        return None
    instance_id = principal_id.split(":", 1)[1]
    if not instance_id.startswith("i-"):
        return None
    reservations = ec2.describe_instances(InstanceIds=[instance_id])
    for reservation in reservations["Reservations"]:
        for instance in reservation["Instances"]:
            return instance.get("PrivateIpAddress")
    return None


def egress_bytes(src_addr, start, end):
    """Sum external egress bytes for one source address."""
    query = f"""
    fields srcAddr, dstAddr, bytes
    | filter action = "ACCEPT" and srcAddr = "{src_addr}"
    | filter dstAddr not like /^10\\./
            and dstAddr not like /^192\\.168\\./
            and dstAddr not like /^172\\.(1[6-9]|2[0-9]|3[0-1])\\./
    | stats sum(bytes) as totalBytes
    """
    rows = run_query(FLOWLOGS_LOG_GROUP, query, start, end)
    if rows and rows[0].get("totalBytes"):
        return int(rows[0]["totalBytes"])
    return 0


def lambda_handler(event, context):
    try:
        # 1-hour lookback absorbs CloudTrail's 5-15 min delivery latency;
        # correlation happens on eventTime via 10-min bins in the query below.
        end = int(time.time())
        start = end - 3600  # 1 hour lookback
        allowed = EXPECTED_READERS.get(BUCKET, [])

        access_query = f"""
        fields userIdentity.arn, userIdentity.principalId
        | filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
        | filter requestParameters.bucketName = "{BUCKET}"
        | stats count(*) as objectReads
                by userIdentity.arn, userIdentity.principalId, bin(10m)
        | filter objectReads > {THRESHOLD}
        """

        for row in run_query(CLOUDTRAIL_LOG_GROUP, access_query, start, end):
            principal = row.get("userIdentity.arn")
            if not principal or principal in allowed:
                continue

            message = (
                f"Principal {principal} read {row.get('objectReads')} "
                f"objects from {BUCKET}."
            )

            ip = private_ip_for_principal(row.get("userIdentity.principalId", ""))
            if ip and egress_bytes(ip, start, end) > 1_000_000_000:
                message += (
                    f" The same source ({ip}) also sent a large volume of "
                    f"data to external destinations in the same window."
                )

            sns.publish(
                TopicArn=SNS_TOPIC,
                Subject="Unexpected S3 access detected",
                Message=message,
            )
    except ClientError as error:
        logger.error(f"AWS API error: {error}")
        raise
    except Exception as error:
        logger.error(f"Unexpected error: {error}")
        raise
    finally:
        logger.info("Correlation check completed")

  1. On the Configuration tab, choose General configuration, then choose Edit. Set Timeout to 5 minutes (300 seconds). CloudWatch Logs Insights queries run asynchronously and can take 30 to 60 seconds against large log groups. Choose Save.
  2. On the Configuration tab, choose Environment variables, then choose Edit, and add CLOUDTRAIL_LOG_GROUP, FLOWLOGS_LOG_GROUP, SNS_TOPIC_ARN, SENSITIVE_BUCKET, and THRESHOLD_READS.
  3. On the Configuration tab, choose Permissions, open the execution role, and attach the following least-privilege policy.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["logs:StartQuery", "logs:GetQueryResults"],
      "Resource": [
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:aws-cloudtrail-logs-my-trail:*",
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:vpc-flow-logs:*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": "ec2:DescribeInstances",
      "Resource": "*"
    },
    {
      "Effect": "Allow",
      "Action": "sns:Publish",
      "Resource": "arn:aws:sns:REGION:ACCOUNT-ID:security-correlation-alerts"
    }
  ]
}

Replace REGION, ACCOUNT-ID, and the log-group names with your values. The ec2:DescribeInstances action doesn’t support resource-level permissions, so Resource: "*" is required for that statement; the other statements are scoped to specific ARNs.

To schedule automated runs

Amazon EventBridge (a serverless event bus that connects applications using events) runs targets on a schedule. Create one from the command line, using the role you made earlier.

aws scheduler create-schedule \
  --name s3-access-correlation-hourly \
  --schedule-expression "rate(1 hour)" \
  --target "Arn=arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction,RoleArn=arn:aws:iam::ACCOUNT-ID:role/EventBridgeSchedulerRole" \
  --flexible-time-window "Mode=OFF"

Step 6: Add enrichment context (optional)

Enrichment cuts triage time by adding an independent signal, but it isn’t required for the correlation to work. This step adds costs. You pay your geolocation provider for API calls, and the additional Lambda execution time increases your Lambda charges. To add IP geolocation, sign up for a geolocation API, add this function to the code, and call it where the handler resolves an IP.

import urllib.request
import json

def geo_context(ip_address):
    """Enrich an IP address with geolocation data from your provider."""
    try:
        url = f"https://your-geolocation-api.example/json/{ip_address}"
        with urllib.request.urlopen(url, timeout=5) as response:
            data = json.load(response)
        return {
            "country": data.get("country_name"),
            "city": data.get("city"),
            "org": data.get("org"),
        }
    except Exception as error:
        logger.warning(f"Geolocation lookup failed for {ip_address}: {error}")
        return None

Inside the handler’s loop, after you resolve ip, append the location to the alert.

            if ip:
                geo = geo_context(ip)
                if geo:
                    message += (
                        f" Source location: {geo['city']}, "
                        f"{geo['country']} ({geo['org']})."
                    )

Step 7: Scale to additional patterns and accounts

As your library grows, move the logic into automated pipelines with EventBridge, Lambda, and AWS Step Functions (a serverless orchestration service that coordinates multiple services into workflows), and surface correlations next to findings in Security Hub. For cross-service correlation at scale, CloudWatch unified data and telemetry capabilities can convert security and compliance data into the OCSF format and let you query sources such as CloudTrail, VPC Flow Logs, and DNS logs from one interface. Security Lake with Athena is a strong option for long-term analysis. Choose the endpoint that fits your retention and query needs.

Figure 3 shows a correlation pipeline built on AWS services including EventBridge, Lambda, Step Functions, and AWS Security Hub. The pipeline runs from data sources through scheduled queries and enrichment to automated response and centralized visibility.

Figure 3: A correlation pipeline built on AWS services

Figure 3: A correlation pipeline built on AWS services

Conclusion

You now have four correlation patterns that layer your business context on top of GuardDuty Extended Threat Detection to catch attacks specific to your environment. A few principles carry across every correlation you build.

  • Identity is your primary correlation key: Track the same principal across services.
  • Time windows matter, but they depend on the attack: Events minutes apart are usually related for fast, automated sequences; the ten-minute bins here work for that pattern. Slow or manual reconnaissance can stretch across hours or days, so widen the window when the pattern is deliberate rather than automated.
  • Context is what you add: Your data classification, access norms, resource ownership, and change windows are signals you bring to detection.
  • Start with one rule: A single well-tuned correlation catches more significant activity than a wall of uncorrelated alerts.

GuardDuty Extended Threat Detection handles the multi-stage patterns common across customers. The correlations in this post add the layer that only your business context can supply. Start with one pattern this week, validate it against your own traffic, and add the next pattern after the first proves reliable.

Have you built correlation rules for patterns not covered here? Share your experience in the Comments section below.

Further reading
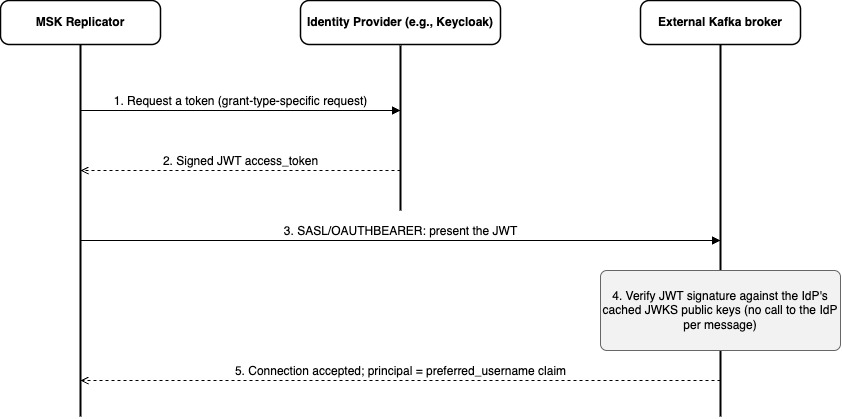
 

Nisha Kashyap

Nisha Kashyap

Nisha Kashyap is a Senior Support Security Engineer at AWS. She works on threat detection and security operations, helping customers investigate security events and build detection that connects signals across AWS services and reflects their own environment.

Gallup scales real-time coaching for thousands with Amazon Bedrock

Post Syndicated from Tamil Sambasivam original https://aws.amazon.com/blogs/architecture/gallup-delivers-real-time-workplace-coaching-to-thousands-of-leaders-with-amazon-bedrock/

How Gallup turned 90 years of workplace science into an AI assistant that gives leaders personalized guidance in seconds, powered by Amazon Bedrock.

Gallup delivers analytics and advice to help leaders and organizations solve their most pressing problems. With more than 90 years of experience and a global reach, Gallup has developed a uniquely deep understanding of workplace behavior and performance.

However, this knowledge wasn’t centralized or delivered in context. Leaders had to navigate multiple resources to find relevant insights and then translate them into action without guidance. The lack of real-time, personalized recommendations meant workplace challenges were often handled reactively instead of proactively.

Gallup needed to transform decades of proprietary research into real-time, personalized guidance that leaders can access instantly within their existing workflow.

In this post, we show how Gallup built Gallup AI, a generative AI assistant powered by Amazon Bedrock. It transforms decades of proprietary workplace research into real-time, personalized coaching delivered directly within the Gallup Access application.

Why Amazon Bedrock

Gallup evaluated multiple approaches to building a generative AI assistant. The team chose Amazon Bedrock for three reasons:

  1. Access to leading foundation models like Anthropic’s Claude without managing infrastructure.
  2. Built-in retrieval augmented generation (RAG) through Amazon Bedrock Knowledge Bases, a fully managed RAG capability, grounds responses in verified research.
  3. Native guardrails to enforce content safety at scale.

This combination allowed Gallup to move from prototype to production in weeks rather than months, without hiring a dedicated machine learning (ML) operations team.

Note: Anthropic’s Claude models on Amazon Bedrock are available in select AWS Regions. For current model and Region availability, see Supported models by Region in Amazon Bedrock.

The approach: Building intelligence into daily workflow

Gallup built Gallup AI, a generative AI-powered assistant integrated directly into Gallup Access. The unified application lets managers review engagement results, build action plans, explore CliftonStrengths insights, and access curated content to better support their teams.

The solution uses Amazon Bedrock with Anthropic’s Claude models to deliver conversational insights grounded in Gallup’s proprietary research. Amazon Bedrock Knowledge Bases and Amazon Kendra retrieve relevant research and organizational data. This is designed to ground responses in verified workplace science. Amazon Bedrock Guardrails enforce content safety policies, while AWS Lambda with FastAPI delivers real-time streaming responses that feel natural and immediate.

The architecture follows a serverless design and supports multiple organizations simultaneously. Amazon ElastiCache Serverless provides sub-millisecond response times for conversation history. Amazon Relational Database Service (Amazon RDS) for MySQL serves as the durable system of record. Amazon Data Firehose streams usage metrics to Amazon Simple Storage Service (Amazon S3) for cost management and performance optimization.

How the solution works

The following diagram shows the Gallup Access AI application architecture.

Architecture diagram of the Gallup Access AI application showing request flow through AWS Lambda to Amazon Bedrock, with Amazon Bedrock Knowledge Bases and Amazon Kendra for retrieval, Amazon ElastiCache Serverless and Amazon RDS for storage, and Amazon Data Firehose streaming metrics to Amazon S3

Figure 1: Gallup Access AI application architecture

The architecture processes requests through the following stages:

Gallup’s proprietary workplace research covers decades of employee engagement studies, performance data, and organizational insights. The content is stored in Amazon S3 and ingested into Amazon Bedrock Knowledge Bases. The application also continuously crawls the Gallup website to capture the latest research publications, articles, and insights, indexing this content in Amazon Kendra for instant retrieval. This dual approach gives the AI assistant access to both historical research archives and current workplace science, delivering responses grounded in verified, up-to-date knowledge rather than generic advice.

When a leader asks Gallup AI a question, the system retrieves relevant research from both Amazon Bedrock Knowledge Bases and Amazon Kendra. The system scores documents based on confidence thresholds, filters them, and consolidates them before sending them to Claude models in Amazon Bedrock.

The conversation flows through AWS Lambda handlers that manage both real-time streaming (for web clients) and synchronous requests (for backend services). Amazon ElastiCache Serverless caches recent conversation history for instant retrieval, while Amazon RDS for MySQL serves as the durable storage layer with organized records of conversations, prompts, responses, and source citations.

Amazon Bedrock Guardrails apply content safety policies during generation, with the ability to intervene mid-stream if policy violations are detected. Interactions persist before streaming begins, preserving transactional integrity even if connections are interrupted.

AWS Systems Manager Parameter Store serves as the application’s centralized configuration hub, managing AI model settings, content safety policies, and performance thresholds. This allows the team to adjust application behavior instantly, without redeploying code or interrupting service for users.

Amazon DynamoDB provides fast, flexible storage for product-specific insights and contextual data, so the application delivers personalized experiences tailored to each user’s role and workflow.

Comprehensive metrics, including I/O tokens, cached tokens, time-to-first byte, and stop reasons, flow through Amazon Data Firehose to Amazon S3, providing visibility into cost, performance, and usage patterns across the application.

What Gallup has achieved

Gallup has transformed decades of workplace research into an intelligent assistant that delivers measurable value across thousands of organizations. Tasks that previously required navigating reports, articles, and tools now resolve through a single conversational interaction. Time to insight dropped from manual research to real-time, AI-delivered guidance within seconds. The application processes billions of tokens through production interactions, with responses grounded in verified workplace science.

Since launching in June 2024, adoption and engagement have grown rapidly:

Metric Result
Prompts Increased ~7x
Conversations Increased ~4.5x
Active users Increased ~5.5x
Engagement depth Average prompts per conversation increased ~55%, indicating sustained, multi-turn interactions
Response latency Sub-second time-to-first byte (TTFB) for streaming responses. Sub-millisecond session retrieval via Amazon ElastiCache Serverless

What the customer said

Gallup’s Director of Product reflects on what this shift means for how leaders access workplace science:

“Gallup AI represents a fundamental shift in how leaders access workplace science. For decades, our research helped organizations make better decisions, but it often required leaders to search, interpret, and apply those insights themselves. By building on Amazon Bedrock, we’re embedding scientifically grounded guidance directly into the flow of work, giving managers real-time support that is both personalized and actionable.”

— Andrew Bridger, Director of Product, Gallup

With this foundation in place, Gallup is focused on expanding what the application can do next.

What’s next

Gallup’s roadmap focuses on making its expertise more accessible, actionable, and embedded into everyday workflows. A key initiative is the development of an AI-curated prompt library that captures the most common questions managers and leaders ask. This library will help users quickly engage with Gallup AI through proven, high-value prompts grounded in workplace research.

In addition, Gallup is introducing guided coaching experiences built around structured conversation flows. These guided prompts walk managers through well-defined coaching scenarios, such as improving engagement, addressing team challenges, or developing employees, by sequencing prompts and responses into purposeful, outcome-driven interactions.

Gallup is building an agent-based foundation using Amazon Bedrock AgentCore. This positions Gallup AI to move beyond a user-facing assistant. By surfacing tools, workflows, and proprietary knowledge programmatically, the system can support not only end users but also other systems and integrations across the application.

Conclusion

By combining the generative AI capabilities of Amazon Bedrock with Gallup’s proprietary workplace research, leaders now have instant access to scientifically grounded guidance exactly when they need it. The serverless architecture enables the application to scale reliably while delivering low-latency streaming responses and comprehensive observability.

To build your own generative AI application, get started with Amazon Bedrock. To learn more about grounding responses in your own data, explore Amazon Bedrock Knowledge Bases.

Further reading

About the authors

Closing the AI agent trust gap with graduated autonomy

Post Syndicated from Dev Arora original https://aws.amazon.com/blogs/architecture/closing-the-ai-agent-trust-gap-with-graduated-autonomy/

How much to trust an AI agent is now a daily operational question. Agents read customer data, open tickets, process refunds, and delete accounts, yet most teams pick up a binary: full access or read-only. Full access is risky because agents fail unpredictably. Read-only leaves most of the agent’s value unused. The distance between what an agent could do and what an operator trusts it to do is the agent’s trust gap.

In this post, we describe graduated autonomy, an architectural pattern that closes the gap. Agents earn expanded permissions through sustained reliability and lose them when performance degrades. Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale with any framework or model, provides the runtime, gateway, policy, and evaluation capabilities. Amazon DynamoDB stores trust state. AWS CodePipeline gates delivery on evaluation results. We cover each layer’s responsibility and the key design decision behind it.

The agent trust gap

Identity and access management answers “who can do what?” once, at provisioning. That model assumes that the principal behaves consistently. A large language model agent breaks it: the same agent can be accurate Monday and hallucinated Tuesday after a prompt change or model update.

Closing the gap requires three capabilities raw API logs rarely provide:

  • Visibility. API logs tell engineers what happened but tell a compliance officer nothing about whether an action was safe.
  • Decision provenance. Tracing an action back to the signal that triggered it, the alternatives considered, and the confidence held.
  • Reversibility. Pre-action state capture, so operators can recover from incorrect actions.

The framework that implements this pattern delivers all three through six architectural layers.

Solution overview

The six layers:

  • Scoring engine computes trust from configurable dimensions.
  • Tier system translates sustained scores into autonomy levels.
  • Pre-execution layer blocks dangerous actions before they run.
  • Enforcement layer applies tiers through Cedar policies at the infrastructure level.
  • Post-execution layer evaluates outcomes, records of provenance, and feeds signals back to scoring.
  • Delivery gate keeps degraded agent versions out of production.
Architecture diagram of the trust framework as a clockwise closed loop: the scoring engine produces a weighted trust score from five dimensions, the tier system converts sustained scores into autonomy tiers T1 through T4, the pre-execution and enforcement layers apply the current tier through in-process checks and Cedar policies, and the post-execution layer returns outcome scores, honeypot results, and human overrides to the scoring engine, with an audit trail at the center recording every decision.

Figure 1: The trust framework’s closed loop.

Each layer is replaceable: the scoring model, tier thresholds, pre-execution signals, and evaluation criteria are configuration, not code. Each layer also embodies one deliberate design decision, developed in the following sections:

Layer Key design decision
Scoring engine Safety is an independent floor, never averaged away by strong metrics
Tier system Start every agent at T1. Promote slowly, demote immediately
Pre-execution layer Fast in-process filters are backstopped, never solely trusted
Enforcement layer Deny by default, enforced outside the agent’s process
Post-execution layer Audit records capture pre-action state, making recovery possible
Delivery gate One unauthorized tool call in adversarial tests blocks release

The scoring engine

The scoring engine computes a weighted score from 0 to 100 per agent over a rolling window of 50 actions, from five dimensions:

Dimension Weight What it measures
Accuracy 25% Task completion correctness against expected outcomes
Safety 20% Boundary respect, adversarial content detection, permitted tool adherence
Consistency 20% Behavioral predictability, inverse of tool-use pattern drift
Compliance 20% Reasoning quality before acting, guardrail adherence
Efficiency 15% Execution without unnecessary retries or resource waste

The composite drives dashboards and tier assignment, but safety acts as an independent floor, so a dangerous individual metric never hides strength elsewhere.

The tier system

Every new agent starts at T1, regardless of test performance:

Tier Score range Permissions
T1: Probation 0 to 40 Read and list only. Two tools visible.
T2: Supervised 41 to 70 Add write operations. Human approves high-risk.
T3: Trusted 71 to 90 Execute and modify. Anomalies flagged for review.
T4: Autonomous 91 to 100 Full access. Post-hoc audit only.

Three rules govern transitions:

  • Promotion requires sustained performance. The score must stay above the promotion threshold for the entire rolling window.
  • Demotion is immediate. When safety drops below its floor or injection is detected, the agent moves down.
  • Hysteresis prevents oscillation. Promotion into a tier requires a score 5 points above that tier range floor. Demotion happens at the range floor itself. An agent at a boundary cannot flap between tiers.

Trust state lives in Amazon DynamoDB as a current state record plus a time-series history per agent. Enforcement components read the current tier on every invocation, a lookup DynamoDB typically serves in single-digit milliseconds.

The pre-execution layer

Post-execution evaluation cannot undo damage, so the pre-execution layer evaluates every tool’s call and can block it before execution. It scores six signals independently:

  • Adversarial injection detection. Pattern matching against known injection phrases. One match triggers an instant block and a trust penalty.
  • Sensitive target detection. Regex matching credentials, tokens, and private keys in tool arguments.
  • Dangerous tool detection. Flagging tools that match destructive operation patterns.
  • Behavioral consistency. Comparing the current tool call against the agent’s historical tool-use distribution.
  • Confidence calibration. Comparing stated confidence against historical accuracy. Overconfident failures are penalized at twice the normal rate.
  • Reasoning quality. Checking whether the agent provided reasoning before acting.

These checks are fast first-pass filters, not a complete defense. The enforcement layer’s deny-by-default policies backstop anything they miss.

The enforcement layer

The pre-execution layer is application code inside the agent’s process. The enforcement layer operates outside the agent, at the infrastructure level.

AgentCore Gateway, a capability of Amazon Bedrock AgentCore, sits between the agent and its tools. It routes every MCP tool invocation through Policy in Amazon Bedrock AgentCore, which evaluates Cedar policies with forbid-wins semantics. One satisfied forbid overrides any number of permits. Tier maps to policy state:

  • Probation: A forbid policy blocks write, execute, and delete tool actions.
  • Promotion: The forbid policy is removed, and broader permits take effect.
  • Demotion: The forbid policy is re-applied.

With the policy engine in enforce mode, the Gateway lists only tools that policy could permit, so the tier’s unconditional forbids keep blocked tools out of the listing. The agent is unlikely to call a tool it has never seen. Listing is a meta-action: each invocation is still evaluated separately with full request context, including input parameters. Cedar denies by default. Enforcement never depends on the agent’s choosing to behave. For model-level content safety, Amazon Bedrock Guardrails complements Policy in AgentCore, filtering harmful content and masking sensitive information independent of tier.

The post-execution layer

After every tool call, the system scores the outcome across eight signals, from confidence calibration and behavioral drift to human overrides and retry detection. Every action generates an audit record following the Think, Plan, Act, Observe, Score chain:

  • Think: The agent’s reasoning chain.
  • Plan: Tool selected, input prepared, pre-execution score.
  • Act: Cedar policy matched, Gateway route processed.
  • Observe: Success or failure, output data.
  • Score: Trust impact, per-dimension scores, tier change.

The Plan and Act records capture pre-action state, which is what makes recovery from an incorrect action possible. Operators ask questions in plain English, and a provenance query endpoint returns a human-readable explanation of any decision. Audit entries persist to DynamoDB.

The delivery gate

Each change to the agent’s prompt, configuration, or tool definitions triggers an AWS CodePipeline run. The run deploys the candidate to staging and runs it against ground-truth fixtures with Amazon Bedrock AgentCore Evaluations, a capability of Amazon Bedrock AgentCore. The fixtures include adversarial cases such as prompt injection and data-exfiltration requests. A single unauthorized tool call in any adversarial case fails the gate. The version that passes becomes the last known stable version.

Production monitoring and recovery

The framework injects synthetic honeypot cases with known expected behavior into a small share of traffic. Validation checks the tool-call trajectory (expected tools, expected order, no forbidden tools) rather than nondeterministic natural-language output, so a mismatch signals a real anomaly. Honeypot results stay out of production metrics. When safety drops below the floor, demotion narrows the agent’s permissions, and the framework redeploys the last known stable version. Together they restore known-good code alongside a tighter permission set. The framework also alerts operators.

Operator judgment feeds directly: the rolling rate at which operators reject proposed actions caps the effective safety metric, so 30 percent rejections cap safety at 70. An emergency stop pushes a single Cedar deny-all policy. Once the policy is active, typically within seconds, the Gateway denies all tool invocations without a redeployment. In multi-agent systems, a delegated action’s effective tier is the minimum across the delegation chain, closing the delegation privilege-escalation path.

Conclusion

In this post, we described graduated autonomy, an architectural pattern for closing the agent trust gap. With this pattern in place, your agents hold the autonomy their track record supports.

To get started, take the dimension weights and tier boundaries from the two tables in this post as a starting template for one agent in your fleet. Start that agent at T1. Then follow the Amazon Bedrock AgentCore Evaluations documentation to build the delivery gate, and the Policy in Amazon Bedrock AgentCore documentation to write the tier policies. You can explore these capabilities in the Amazon Bedrock console and on the Amazon Bedrock AgentCore detail page.

For deeper dives into the building blocks this pattern uses, read Secure AI agents with Policy in Amazon Bedrock AgentCore and Build custom code-based evaluators in Amazon Bedrock AgentCore.


About the authors

Amazon MSK Service 101: How many partitions does an Amazon MSK topic need?

Post Syndicated from Yashika Jain original https://aws.amazon.com/blogs/big-data/amazon-msk-service-101-how-many-partitions-does-an-amazon-msk-topic-need/

Customers new to Amazon Managed Streaming for Apache Kafka (Amazon MSK) often ask how many partitions their topics need. Choosing the right partition count is one of the most impactful architectural decisions you make, because it directly affects throughput, scalability, and operational complexity.

In Apache Kafka, a topic is the fundamental unit for categorizing data streams, but to achieve high scalability and performance, Kafka divides topics into smaller, independent units called partitions.

In this post, we provide practical guidance for determining the ideal partition count for your use case.

Understanding Kafka partitions

In
Apache Kafka, a partition is the unit of storage and parallelism. Each partition is an ordered, immutable log that can store records as they are produced to a topic. When you create a topic, Kafka distributes its partitions across the brokers in the cluster. Partitions allow Kafka to scale in three key ways:
  • Parallelism – Within a consumer group, each partition can be read by only one consumer at a time. Each partition maps to a dedicated log file in storage on the broker, and Kafka manages these logs through separate processing threads. This architecture allows more partitions to support more consumers processing data in parallel, with each partition’s log being independently managed for read and write operations.
The following diagram shows how Kafka distributes partition replicas across a three-broker cluster, with each broker serving as a leader for some partitions and a follower for others.
Partitions 0, 1, and 2 replicated across three brokers, each a leader for some partitions and a follower for others

Figure 1: Partition replicas distributed across a three-broker cluster

The following diagram illustrates how producers append new records to the end of a partition log, while consumers read sequentially from their current offset position.

Producers append records to the tail of partition logs while consumers read sequentially from their offset position

Figure 2: Producer writes and consumer offset positions in two partition logs

  • Throughput – Producers and consumers can read and write data in parallel across partitions, increasing overall throughput.
  • Scalability – Partitions allow Kafka to spread data and load across multiple brokers instead of concentrating it on a single node.

However, increasing partitions comes with trade-offs. Each partition adds metadata overhead, consumes memory, and requires file handles on the broker. While more partitions improve throughput and parallelism, they also increase the operational burden on the cluster. Too many partitions can lead to longer leader election times during broker failures, increased end-to-end latency, and higher memory consumption for both producers and consumers managing connections to multiple partitions.

Trade-offs when choosing partition count

Choosing a partition count is a balancing act between parallelism and resource utilization.

Benefits of more partitions

Using more partitions can significantly improve throughput by allowing Kafka to distribute read and write traffic across more brokers. This is particularly useful for high-volume ingestion pipelines and real-time analytics workloads. More partitions also allow consumer groups to scale horizontally, because the maximum number of active consumers in a group is limited by the number of partitions. In addition, choosing a partition count that is evenly divisible by the number of brokers helps provide balanced leadership and replica distribution, reducing the risk of uneven load.

Operational costs of more partitions

However, higher partition counts also come with costs. When a broker fails or undergoes maintenance, Kafka must perform recovery operations for each affected partition. During recovery, Kafka elects new leaders for partitions that were hosted on the unavailable broker and replicates data from the remaining in-sync replicas to newly assigned brokers. This process involves copying partition data across the network to restore the replication factor, which can be resource intensive. As the number of partitions increases, these recovery operations take longer because each partition requires its own leader election and data replication cycle.

You might encounter clusters with very high partition counts that experience extended recovery times during rolling upgrades, even when overall traffic volumes are modest. Amazon MSK Express brokers address this challenge by recovering 90x faster and providing 180x faster elasticity when scaling out clusters. This significantly reduces the operational impact of high partition counts during maintenance windows and failure scenarios.

Infrastructure cost implications

Beyond operational complexity, more partitions can directly increase infrastructure costs. Amazon MSK publishes partition-per-broker limits that vary by instance type. When the total partition count (including replicas) exceeds what the current broker fleet can support, you must add brokers to stay within recommended limits, even if throughput alone does not warrant the additional capacity.

Amazon MSK partition-per-broker guidelines

Amazon MSK publishes recommended partition-per-broker guidelines to help you operate clusters reliably. These values are strict limits. Exceeding them can lead to operational challenges, particularly during broker replacement or rolling upgrades, and can block cluster operations such as configuration updates or scaling down.

Express brokers support up to 5x more partitions per broker compared to Standard brokers. For example, the largest Standard broker (kafka.m7g.16xlarge) supports a recommended maximum of 4,000 partitions per broker. The equivalent Express broker (express.m7g.16xlarge) supports up to 20,000 recommended partitions per broker. This higher partition density means partition-bound workloads can be hosted on fewer brokers, improving price-performance by up to 50% for such workloads.

We recommend setting Amazon CloudWatch alarms on PartitionCount per-broker metrics to proactively monitor your partition distribution. When an alarm triggers, evaluate your partition strategy and consider rebalancing partitions across brokers, consolidating topics, or scaling out your cluster to stay within recommended limits. For detailed guidance, see Right-size your cluster: Number of partitions per Standard broker and Express broker partition quota.

Practical guidance for choosing a partition count

There is no single formula that works for every Kafka workload. In practice, you typically combine several considerations when sizing partitions.

  • Start with throughput requirements – The first step is to determine your per-partition throughput capacity, which then informs how many partitions you need.

For Express brokers, use the per-broker throughput capacity as the primary means for sizing your cluster. Express brokers feature a fully managed storage layer, so you do not need to separately account for storage I/O constraints. The published per-broker limits represent the effective capacity available to your workload.

For Standard brokers, the achievable throughput depends on additional factors beyond the broker instance size. These factors include provisioned EBS storage throughput, the number of consumer groups reading from the broker, and how much data is served from memory versus disk. Storage I/O is consumed when producers write, when data replicates between brokers, and when consumers read data that is not in memory. For this reason, validate the effective per-partition throughput for Standard brokers through load testing in your environment.

Once you know your per-partition throughput, calculate the required number of partitions: Number of partitions = Peak throughput of the topic ÷ Throughput per partition

For example, if a topic must handle 40 MB/sec at peak and your testing shows each partition can sustain 5 MB/sec, you would need: 40 ÷ 5 = 8 partitions. Always validate these assumptions with load testing, as actual throughput varies based on your workload characteristics. For initial sizing estimates, refer to the Amazon MSK Sizing and Pricing worksheet and the Amazon MSK Best Practices documentation.

  • Consider your consumer parallelism needs – If you know the number of consumers required during peak processing times, use that as your partition count. We don’t recommend having more active consumers in a consumer group than partitions. For example, if you have 5 partitions, only 5 consumers can actively process data. Additional consumers remain idle. These idle consumers still maintain active TCP connections to the brokers, sending frequent heartbeats and group coordination requests. This might result in unnecessary overhead on broker resources and contribute to high CPU usage despite low egress traffic.
Consumer group with more consumers than partitions, leaving the extra consumers idle

Figure 3: Idle consumers when a consumer group has more consumers than partitions

  • Producer throughput and partition keys – When sizing partitions, consider producer-side throughput in addition to consumer parallelism. If producers generate data faster than a single partition can handle, additional partitions can help distribute write traffic across brokers. Partition keys also play a critical role. Poorly distributed or low-cardinality keys can create hot partitions and limit throughput. In such cases, increasing the number of partitions alone does not improve throughput unless records are evenly distributed.
  • Plan for even distribution and future growth – Kafka works best when partitions can be spread evenly across brokers. Instead of focusing on specific numbers, aim for partition counts that divide reasonably well across your expected broker count. This reduces reassignment churn when brokers are added or replaced. But avoid excessive over-partitioning. It’s reasonable to leave some headroom for future growth. However, creating thousands of partitions “just in case” often causes more harm than good. Increasing partitions later is supported, but it can affect ordering guarantees and may require consumer changes. Start with a conservative number, monitor real traffic patterns, and scale gradually.

From an operational perspective, Amazon MSK provides recommended partition-per-broker guidelines based on broker instance type. Exceeding these guidelines increases operational risk and can block cluster operations such as version upgrades, scaling, or configuration changes. Large partition counts can also increase consumer group rebalance duration, temporarily pausing message processing and increasing end-to-end latency.

Keep in mind that partitioning improves scalability, but it does not address application-level bottlenecks such as slow consumers, inefficient processing logic, or downstream system constraints.

Conclusion

Determining the right number of partitions for an Amazon MSK topic is a foundational design decision. It affects throughput, scalability, failure recovery, and day-to-day operability of your Kafka cluster. Start by understanding your throughput and consumer parallelism needs, respect Amazon MSK partition-per-broker guidelines, avoid excessive over-partitioning, and validate assumptions through load testing. Most importantly, there is no universal “correct” number, only a number that fits your workload, operational goals, and cost.

For more information, see the Amazon MSK Developer Guide and Recommended best practices for Amazon MSK.


About the authors

Yashika Jain

Yashika Jain

Yashika is a Senior Cloud Analytics Engineer at AWS, specializing in real-time analytics and event-driven architectures. She is committed to helping customers by providing deep technical guidance, driving best practices across real-time data platforms and solving complex issues related to their streaming data architectures.

Ali Alemi

Ali Alemi

Ali is a Principal Streaming Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems which are reliable, secure, efficient, and cost-effective. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the Cloud.

[$] An ongoing 3D-printer AGPL violation

Post Syndicated from jake original https://lwn.net/Articles/1089390/

At FOSSY 2026, several people from the
Software Freedom Conservancy (SFC),
which organizes the conference, gave a presentation about an ongoing
violation
of the Affero General Public
License version 3
(AGPLv3). Bradley Kühn, Karen Sandler, and Denver
Gingerich spoke about different aspects of the violation, which is in
regard to 3D-printer software from Bambu Lab, and what is being
done to try to provide users with alternatives. One aspect that is
particularly interesting is that the circumvention that the company is
employing is precisely what the AGPL was written to prevent.

Armbian 26.8 released

Post Syndicated from jzb original https://lwn.net/Articles/1090741/

Version 26.8 of
the Armbian distribution for Arm hardware has
been released.

Most releases are a long list of small improvements. This one had three
larger pieces landing at roughly the same time, and all three touch parts of
Armbian that people use directly rather than parts they only read about in
changelogs.

The installer was rewritten. Armbian Imager reached 2.0. And our CI moved out
of the repository it had outgrown into one built for the job. None of these were
planned to coincide; they simply reached the point where postponing them again
would have cost more than doing them.

The installer rewrite is the one I expect people to notice first. It now
ships as an armbian-config module, which means it is unit-tested, the same way
the rest of armbian-config is tested, rather than living as a script that
everyone was slightly afraid to touch. It can target SPI and MTD, treats eMMC
and NVMe as separate flows instead of pretending they are the same thing, can
flash a bootloader on its own, and — this one is overdue — reports when a
bootloader write fails instead of printing “Done.” and leaving you to find out
at the next boot.

See the release notes
for a full list of changes.

The collective thoughts of the interwebz