Tag Archives: Amazon Route 53

Detecting multi-stage attacks on AWS: A guide to cross-service signal correlation

Post Syndicated from Nisha Kashyap original https://aws.amazon.com/blogs/security/detecting-multi-stage-attacks-on-aws-a-guide-to-cross-service-signal-correlation/

A single alert from one security service tells you something happened. Read that signal alongside activity from other services and your own business context, and you will know whether what happened is part of a multi-stage attack.

Consider a short sequence. An identity calls GetCallerIdentity from a source address it hasn’t previously used. Within minutes, that same identity runs a burst of List and Describe calls across several services, and some of them fail with AccessDenied. Soon after, a large volume of data leaves your environment toward a domain that was registered last week. Amazon GuardDuty might already flag pieces of this, such as the reconnaissance from an unfamiliar source, through finding types like Recon:IAMUser/* or Discovery:S3/*. What you gain from correlating the pieces yourself is a single view of the sequence, tied to your own business context, so you can act on the whole rather than triaging findings one at a time.

This post is for security engineers and security operations teams who run Amazon Web Services (AWS) detection services and want to catch patterns specific to their environment. You will see how AWS detection and your business context fit together, and how to build correlations that use that context. The examples run in Amazon CloudWatch Logs Insights so you can try them today, and the closing section describes how to grow them into an automated pipeline. The walkthrough later in this post lists the prerequisites for these queries.

Start with AWS detection services

Begin with the AWS detection services. They cover the threats common across customers, and everything in this post is built on them.

Turn these on and tune them before you build anything custom. Tuning means adjusting sensitivity to reduce false positives for your environment, choosing which data sources each service monitors, and suppressing findings for known-good patterns.

GuardDuty correlates multi-stage attacks for you

Before you build anything by hand, see what GuardDuty already does for you. Amazon GuardDuty Extended Threat Detection correlates signals across multiple data sources including AWS CloudTrail, Amazon S3 data events, runtime monitoring, Amazon Elastic Kubernetes Service (Amazon EKS) audit logs, and more, then raises a single critical severity attack sequence finding when it spots a multi-stage pattern. It recognizes sequences such as credential compromise followed by data exfiltration, maps them to MITRE ATT&CK tactics, and attaches a timeline and remediation guidance. If you have GuardDuty enabled today, then GuardDuty Extended Threat Detection is already enabled by default and needs no queries from you. For details on how GuardDuty charges apply, see Amazon GuardDuty pricing.

The credential compromise sequence in the opening example is the kind of universal pattern GuardDuty Extended Threat Detection is built to catch, so rely on it for those. Attack sequence findings show up in the GuardDuty console next to your other findings, and they route to Security Hub and your response workflows the same way.

GuardDuty handles the threats that look the same in every account. What it doesn’t have is the context that makes a given action suspicious in your account. That’s what you provide.

Add your business context

Business context is what only you know about your environment: which buckets hold sensitive data, which principals have a reason to touch which resources, which role chains your policy permits, and when your production change windows open. GuardDuty Extended Threat Detection learns from patterns common across customers, but it can’t answer these environment-specific questions. Express them as correlations and you add a detection layer tuned to your environment. Each of the following four patterns turns one of these facts into a query.

Run these queries in the AWS Management Console for CloudWatch by choosing Logs, then Logs Insights, using the CloudWatch Logs Insights query language. Most read CloudTrail events from a CloudWatch Logs log group that your trail delivers to. If your trail writes only to Amazon S3, add CloudWatch Logs delivery on the trail, or run equivalent queries in Amazon Athena (a serverless query service for analyzing data in Amazon S3 using SQL).

Note: The queries and code in this post use placeholder values. Replace them with your own before running: your-sensitive-bucket (your S3 bucket name), your-key-id (your AWS KMS key ID), region (your AWS Region, such as us-east-1), account-id (your 12-digit AWS account ID), and aws-cloudtrail-logs-my-trail (your CloudTrail log group name).

A note on multi-account environments. In AWS Organizations, an organization trail delivers every account’s events to one log group, so these queries work as-is but return cross-account results. Filter by recipientAccountId for account-scoped views. Without an organization trail, run queries per account or use Amazon Security Lake as a central query surface.

The attack chain mapped to AWS services

Multi-stage attacks move through five phases, and each phase leaves a signal in a different service. These signals surface across three log sources: CloudTrail, which records API activity in your account; Amazon VPC Flow Logs, which capture network connection metadata; and Amazon Route 53 Resolver query logs, which record DNS queries from your VPCs.

  • Initial access – Stolen credentials reach your environment. CloudTrail records GetCallerIdentity, GetSessionToken, or AssumeRole from an unfamiliar source.
  • Discovery – The threat actor enumerates with List, Describe, and Get calls, often triggering AccessDenied responses.
  • Privilege escalation – The threat actor chains roles or edits policies. CloudTrail records AssumeRole sequences, PutRolePolicy, or CreateAccessKey.
  • Lateral movement – The threat actor moves across accounts or AWS Regions, assuming roles and creating resources in unfamiliar places.
  • Exfiltration – Data leaves through GetObject calls at scale, large outbound transfers in VPC Flow Logs, and DNS queries in Route 53 Resolver query logs to recently registered domains.

Figure 1 shows the five attack phases mapped to the AWS log source that records each one.
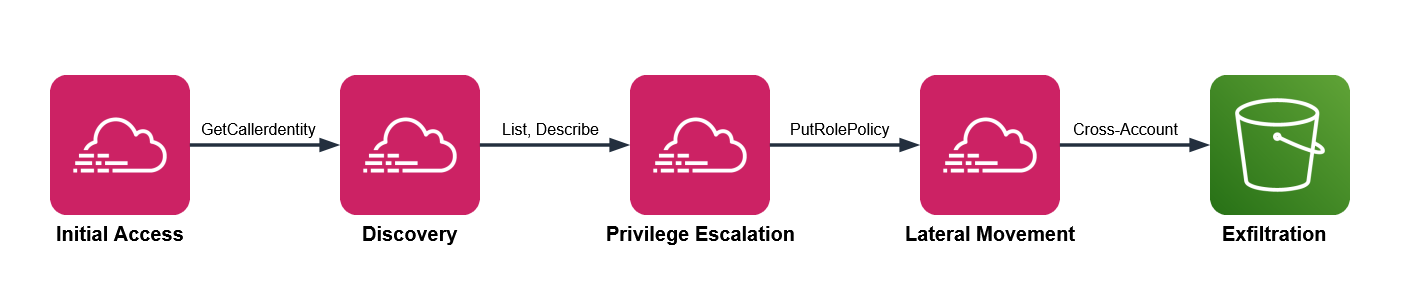
Figure 1: Attack chain mapped to AWS services

Figure 1: Attack chain mapped to AWS services

GuardDuty Extended Threat Detection watches this chain for universal patterns. The four patterns that follow add the dimension you supply: your business context.

Pattern one: Sensitive data access by an unexpected principal

Your data classification and access norms drive this detection. One bucket holds customer records, another holds public web assets, and you know which principals have a reason to read the customer records, which are sensitive. Encode that knowledge and an ordinary looking read turns into something worth chasing.

Three signals converge here. CloudTrail shows GetObject at volume on a bucket you’ve classified as sensitive. The principal isn’t on your list of expected readers for that bucket. And VPC Flow Logs show a large outbound transfer from the same source in the same window, while DNS query logs show a recently registered destination domain, which together increase your confidence that there’s a potential threat.

CloudTrail management events don’t record GetObject. You must turn on CloudTrail data events for the buckets you care about to capture GetObject. Many teams miss GetObject because data events weren’t enabled on the relevant buckets.

This query shows bulk reads on a sensitive bucket, grouped by principal. Run it in CloudWatch Logs Insights with your CloudTrail log group selected.

fields @timestamp, userIdentity.arn, requestParameters.bucketName
| filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
| filter requestParameters.bucketName = "your-sensitive-bucket"
| stats count(*) as objectReads,
        count_distinct(requestParameters.key) as distinctObjects
        by userIdentity.arn, bin(10m)
| filter objectReads > 100
| sort objectReads desc

The threshold of 100 is a placeholder. Run the query over a week of normal activity, find the ninety-fifth percentile read count for that bucket, and set the threshold above it. Then check each principal the query returns against your expected reader list. A principal that isn’t on the list, reading at volume, is the result to investigate.

To corroborate, look for a matching outbound transfer. Switch the log group selector to your VPC Flow Logs log group and run this.

fields @timestamp, srcAddr, dstAddr, bytes
| filter action = "ACCEPT"
# exclude RFC 1918 private ranges so only external destinations remain
| filter dstAddr not like /^10\./
        and dstAddr not like /^192\.168\./
        and dstAddr not like /^172\.(1[6-9]|2[0-9]|3[0-1])\./
| stats sum(bytes) as totalBytes by srcAddr, dstAddr, bin(10m)
| filter totalBytes > 1000000000
| sort totalBytes desc

The Amazon S3 query returns a principal, and the Flow Logs query works on IP addresses, so you translate one into the other. The worked example later in this post covers that translation in full.

Picture an analytics role that reads a reporting bucket all day. One afternoon, it reads a thousand objects from your customer records bucket instead. GuardDuty stays quiet, because an authenticated role making valid GetObject calls isn’t suspicious anywhere else. Your query flags it, because that role isn’t on the expected reader list for that bucket. The classification you applied is what turns silence into a signal.

Figure 2 shows a bulk read from a sensitive bucket in CloudTrail, a large outbound transfer in VPC Flow Logs, and a young domain resolution in Route 53 Resolver logs.
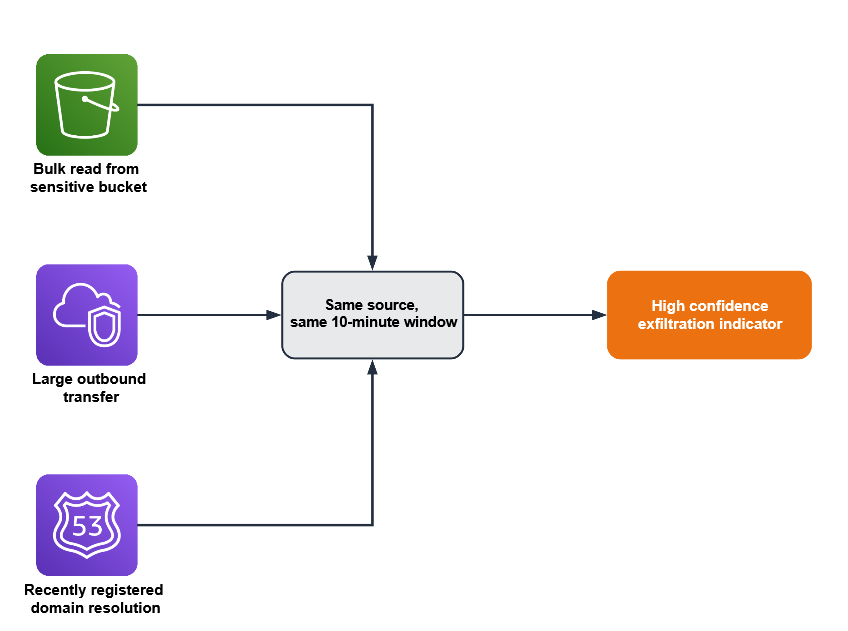
Figure 2: Three signals converging within a single time window to indicate exfiltration

Figure 2: Three signals converging within a single time window to indicate exfiltration

Pattern two: A role chain that crosses your access policy

Picture a deployment that assumes one role to build, then a second to release. For one principal, that two-hop AssumeRole chain is routine; for a different principal it’s a policy violation. This pattern relies on your trust topology—the chains your organization permits—so put that knowledge in the query.

This pattern needs three conditions:

  • CloudTrail shows several AssumeRole calls from the same source inside a short window
  • The chain ends in a sensitive action such as CreateAccessKey, PutRolePolicy, or AttachUserPolicy
  • The starting identity isn’t one your policy expects to run that chain

In CloudWatch Logs Insights, select your CloudTrail log group and run this query, which surfaces chains of two or more hops.

fields @timestamp, userIdentity.arn, requestParameters.roleArn, sourceIPAddress
| filter eventName = "AssumeRole"
| stats count(*) as assumeCount,
        count_distinct(requestParameters.roleArn) as rolesAssumed
        by sourceIPAddress, bin(5m)
| filter assumeCount >= 2 and rolesAssumed >= 2
| sort assumeCount desc

Two hops is the minimum for a chain; raise the count if your environment chains roles often. Your deployment pipeline probably assumes several roles an hour, as do AWS service principals such as AWS Security Hub. Exclude the identities you expect to see assuming multiple roles, including your pipeline role and known AWS service principals. What’s left is the set to investigate, such as a person assuming several roles at an odd hour and ending in a new access key. Treat that distinction as data: list the identities and actions you consider normal, and review the chains that fall outside the list.

Pattern three: An encryption key used outside its owning workload

Resource ownership is the signal here. A given AWS Key Management Service (AWS KMS) key creates and controls the encryption keys for a workload, and a single key should serve a single workload, such as a payments service. A Decrypt call against it is a valid, authorized API action, so nothing about the call itself looks wrong. The ownership rule you set is what makes another principal’s use of the key worth a second look.

This pattern applies only to customer-managed keys scoped to one workload. It doesn’t apply to AWS-managed keys (alias/aws/*) or to customer-managed keys intentionally shared across services. Confirm single-workload intent from the key policy’s Principal block before deploying this rule.

Two conditions indicate misuse:

  • CloudTrail shows Decrypt or GenerateDataKey calls on a key that’s tied to one workload
  • The calling principal isn’t the role that owns that workload

Against your CloudTrail log group, run this query to list the principals that called a specific key.

fields @timestamp, userIdentity.arn, eventName
| filter eventSource = "kms.amazonaws.com"
| filter eventName in ["Decrypt", "GenerateDataKey", "Encrypt"]
| filter resources.0.ARN = "arn:aws:kms:region:account-id:key/your-key-id"
| stats count(*) as keyUses by userIdentity.arn, eventName
| sort keyUses desc

Compare what comes back against the one workload role you expect. A principal you don’t recognize on that key is the signal. Because key misuse is an early move in data theft, this correlation catches activity that only your ownership knowledge can flag.

Consider a key that wraps your payments database. The payments service role calls it in normal operation, and nothing else should. If a developer role or a freshly created role runs Decrypt against it, the call succeeds and reads as ordinary in isolation. The reason it matters is the ownership rule you hold in your head and now state in this query.

Pattern four: A privileged action outside your change window

Start with the query, then read what it means.

fields @timestamp, userIdentity.arn, eventName, sourceIPAddress
| filter eventName in ["PutRolePolicy", "AttachRolePolicy",
        "CreateAccessKey", "AuthorizeSecurityGroupIngress", "PutBucketPolicy"]
| stats count(*) as sensitiveChanges by userIdentity.arn, eventName, sourceIPAddress
| sort sensitiveChanges desc

Run it against your CloudTrail log group, scoped to your off-hours window when you schedule it, so it returns only activity outside the change window. Your change process defines what normal looks like here: production security and identity changes flow through a pipeline during defined hours, run by a known actor. A console-driven policy change at 2:00 AM, made by a person rather than the pipeline, doesn’t fit those expectations. The signal is a sensitive change such as PutRolePolicy or AuthorizeSecurityGroupIngress, made outside the window, by a person rather than your pipeline role.

Exclude the actors you expect, such as your deployment pipeline role, your patch automation role, and AWS service principals like AWS CloudFormation and AWS Systems Manager. What remains is privileged change made outside your process, which is both what an attacker does to establish persistence and what your own change discipline says shouldn’t happen.

Your pipeline might open security group rules during a deployment every weekday afternoon. A person opening a security group rule at midnight on a weekend is the same API call carrying a very different meaning. The schedule and the actor, both facts you define, are what separate the two.

Build your first correlation rule

The following walkthrough uses pattern one as a complete example. The other three patterns follow the same design with their own queries.

Prerequisites

These prerequisites feed the queries in this walkthrough. Confirm each one before you start:

  • A CloudTrail trail logging management events to a CloudWatch Logs log group
  • CloudTrail data events enabled for your sensitive S3 buckets
  • GuardDuty enabled, with its protection plans and Extended Threat Detection
  • VPC Flow Logs on for your production VPCs
  • Amazon Route 53 Resolver query logging on

CloudTrail, GuardDuty, VPC Flow Logs, and Route 53 Resolver query logging provide the raw signals that your correlations connect. Without them, the queries in this post return empty results.

Step 1: Record the bucket and its expected readers

Choose one sensitive bucket to monitor, and write down the principals allowed to read it. Store the list where your automation can reach it, such as a configuration file in version control or an Amazon DynamoDB table (a managed NoSQL database).

{
  "customer-records-prod": [
    "arn:aws:iam::123456789012:role/AnalyticsPipeline",
    "arn:aws:iam::123456789012:role/ComplianceAudit"
  ],
  "financial-data-archive": [
    "arn:aws:iam::123456789012:role/FinanceReporting"
  ]
}

This example hardcodes the list for simplicity. In production, load it from a DynamoDB table or Parameter Store so you can update it without redeploying.

Step 2: Baseline before you set a threshold

Run the pattern one query over one week of normal activity. Find the 95th percentile read count for the bucket and use a value greater than that as your alert threshold. This step keeps legitimate high-volume access from generating false positives later.

Set the THRESHOLD_READS environment variable to this value when you configure the function in Step 5.

Step 3: Run the access query

In the CloudWatch console:

  1. Choose Logs, then choose Logs Insights.
  2. In the Select log group(s) dropdown, select your CloudTrail log group.
  3. Set the time range to 3h (the last three hours).
  4. In the query editor, paste the pattern one query.
  5. Replace your-sensitive-bucket with your bucket name.
  6. Choose Run query.
  7. Review the principals in the results table.
  8. Compare each principal against your expected reader list from step 1, and flag any that are not on it.

Each result includes a principal that step 4 translates into an IP address.

Step 4: Correlate with network activity

CloudTrail logs actions by AWS Identity and Access Management (IAM) principal, while VPC Flow Logs record traffic by IP address. To connect the two signals, translate the principal into its address.

For a role attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the userIdentity.principalId field includes the instance ID after the colon, in the form AROAEXAMPLE:i-1234567890abcdef0. Copy the instance ID and look up its private IP address.

aws ec2 describe-instances \
  --instance-ids i-1234567890abcdef0 \
  --query "Reservations[0].Instances[0].PrivateIpAddress" \
  --output text

Other compute types differ. A VPC-connected AWS Lambda function sends traffic through elastic network interfaces in your subnets, so correlate on those interface addresses. An Amazon Elastic Container Service (Amazon ECS) task records its network interface in task metadata. For a plain assumed-role session with no instance behind it, the sourceIPAddress field in CloudTrail already holds the caller’s address, so you correlate on it directly.

Run the Flow Logs query from pattern one, filtering srcAddr to that address within 10 minutes of the Amazon S3 read timestamp. A match places the same source behind both the sensitive read and a large external transfer in one window. CloudTrail events reach CloudWatch Logs 5–15 minutes after the API call, so correlate on eventTime rather than query time. Query a wider lookback than your correlation window: for example, look back 30 to 60 minutes but correlate on a 10-minute eventTime window. Steps 3 and 4 are manual validation; step 5 automates them.

Figure 2 shows DNS resolution as a third corroborating signal. This walkthrough implements the CloudTrail and VPC Flow Logs correlation. To add DNS, apply the same run_query() pattern against your Route 53 Resolver query log group.

Step 5: Automate the check

Move the query into a Lambda function (serverless compute that runs your code without a server to manage), send results to a notification channel, and schedule regular runs. Work through the following sub-procedures.

To create the notification channel

  1. Open the Amazon Simple Notification Service (Amazon SNS) console. Amazon SNS is a managed messaging service that delivers notifications to subscribers.
  2. In the navigation pane, choose Topics.
  3. Choose Create topic.
  4. For Type, select Standard.
  5. For Name, enter security-correlation-alerts.
  6. Choose Create topic.
  7. Note the topic Amazon Resource Name (ARN) at the top of the topic details page. You will use it in the function.
  8. Choose Create subscription.
  9. For Protocol, select Email.
  10. For Endpoint, enter your email address or incident management endpoint.
  11. Choose Create subscription, then confirm the subscription from the email AWS sends.

To create the EventBridge Scheduler execution role

The schedule needs a role that lets it invoke your function, and its trust policy needs conditions that pin the role to the schedule you own. Without those conditions, another account with access to the scheduler service could theoretically call this role; a class of misuse known as the confused deputy problem.

1. Create a trust policy file named scheduler-trust-policy.json.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": { "Service": "scheduler.amazonaws.com" },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringEquals": {
          "aws:SourceAccount": "ACCOUNT-ID"
        },
        "ArnLike": {
          "aws:SourceArn": "arn:aws:scheduler:REGION:ACCOUNT-ID:schedule/*/s3-access-correlation-hourly"
        }
      }
    }
  ]
}

2. Create the role, then attach permission to invoke the function. Scope Resource to the specific function ARN so this role can’t invoke anything else.

aws iam create-role \
  --role-name EventBridgeSchedulerRole \
  --assume-role-policy-document file://scheduler-trust-policy.json

aws iam put-role-policy \
  --role-name EventBridgeSchedulerRole \
  --policy-name LambdaInvokePolicy \
  --policy-document '{
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "Allow",
        "Action": "lambda:InvokeFunction",
        "Resource": "arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction"
      }
    ]
  }'

When you create the function, Lambda automatically creates an execution role. You will attach the permissions this function needs to that role in a later step.

To deploy the correlation function

  1. Open the Lambda console.
  2. Choose Create function.
  3. For Function name, enter CorrelationFunction.
  4. For Runtime, select the latest Python runtime.
  5. Choose Create function.
  6. On the Code tab, replace the default code with the following function, then choose Deploy.
import os
import time
import logging
import boto3
from botocore.exceptions import ClientError

logger = logging.getLogger()
logger.setLevel(logging.INFO)

logs = boto3.client("logs")
sns = boto3.client("sns")
ec2 = boto3.client("ec2")

CLOUDTRAIL_LOG_GROUP = os.environ["CLOUDTRAIL_LOG_GROUP"]
FLOWLOGS_LOG_GROUP = os.environ["FLOWLOGS_LOG_GROUP"]
SNS_TOPIC = os.environ["SNS_TOPIC_ARN"]
BUCKET = os.environ["SENSITIVE_BUCKET"]
THRESHOLD = int(os.environ.get("THRESHOLD_READS", "100"))

# Expected readers per bucket
EXPECTED_READERS = {
    "customer-records-prod": [
        "arn:aws:iam::123456789012:role/AnalyticsPipeline",
        "arn:aws:iam::123456789012:role/ComplianceAudit",
    ],
}


def run_query(log_group, query, start, end):
    """Start a Logs Insights query and wait for it to finish."""
    started = logs.start_query(
        logGroupName=log_group,
        startTime=start,
        endTime=end,
        queryString=query,
    )
    query_id = started["queryId"]
    while True:
        outcome = logs.get_query_results(queryId=query_id)
        if outcome["status"] in ("Complete", "Failed", "Cancelled"):
            break
        time.sleep(1)
    if outcome["status"] != "Complete":
        raise RuntimeError(f"Query did not complete: {outcome['status']}")
    return [{f["field"]: f["value"] for f in row} for row in outcome["results"]]


def private_ip_for_principal(principal_id):
    """Resolve an EC2 instance role principalId to its private IP."""
    if ":" not in principal_id:
        return None
    instance_id = principal_id.split(":", 1)[1]
    if not instance_id.startswith("i-"):
        return None
    reservations = ec2.describe_instances(InstanceIds=[instance_id])
    for reservation in reservations["Reservations"]:
        for instance in reservation["Instances"]:
            return instance.get("PrivateIpAddress")
    return None


def egress_bytes(src_addr, start, end):
    """Sum external egress bytes for one source address."""
    query = f"""
    fields srcAddr, dstAddr, bytes
    | filter action = "ACCEPT" and srcAddr = "{src_addr}"
    | filter dstAddr not like /^10\\./
            and dstAddr not like /^192\\.168\\./
            and dstAddr not like /^172\\.(1[6-9]|2[0-9]|3[0-1])\\./
    | stats sum(bytes) as totalBytes
    """
    rows = run_query(FLOWLOGS_LOG_GROUP, query, start, end)
    if rows and rows[0].get("totalBytes"):
        return int(rows[0]["totalBytes"])
    return 0


def lambda_handler(event, context):
    try:
        # 1-hour lookback absorbs CloudTrail's 5-15 min delivery latency;
        # correlation happens on eventTime via 10-min bins in the query below.
        end = int(time.time())
        start = end - 3600  # 1 hour lookback
        allowed = EXPECTED_READERS.get(BUCKET, [])

        access_query = f"""
        fields userIdentity.arn, userIdentity.principalId
        | filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
        | filter requestParameters.bucketName = "{BUCKET}"
        | stats count(*) as objectReads
                by userIdentity.arn, userIdentity.principalId, bin(10m)
        | filter objectReads > {THRESHOLD}
        """

        for row in run_query(CLOUDTRAIL_LOG_GROUP, access_query, start, end):
            principal = row.get("userIdentity.arn")
            if not principal or principal in allowed:
                continue

            message = (
                f"Principal {principal} read {row.get('objectReads')} "
                f"objects from {BUCKET}."
            )

            ip = private_ip_for_principal(row.get("userIdentity.principalId", ""))
            if ip and egress_bytes(ip, start, end) > 1_000_000_000:
                message += (
                    f" The same source ({ip}) also sent a large volume of "
                    f"data to external destinations in the same window."
                )

            sns.publish(
                TopicArn=SNS_TOPIC,
                Subject="Unexpected S3 access detected",
                Message=message,
            )
    except ClientError as error:
        logger.error(f"AWS API error: {error}")
        raise
    except Exception as error:
        logger.error(f"Unexpected error: {error}")
        raise
    finally:
        logger.info("Correlation check completed")

  1. On the Configuration tab, choose General configuration, then choose Edit. Set Timeout to 5 minutes (300 seconds). CloudWatch Logs Insights queries run asynchronously and can take 30 to 60 seconds against large log groups. Choose Save.
  2. On the Configuration tab, choose Environment variables, then choose Edit, and add CLOUDTRAIL_LOG_GROUP, FLOWLOGS_LOG_GROUP, SNS_TOPIC_ARN, SENSITIVE_BUCKET, and THRESHOLD_READS.
  3. On the Configuration tab, choose Permissions, open the execution role, and attach the following least-privilege policy.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["logs:StartQuery", "logs:GetQueryResults"],
      "Resource": [
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:aws-cloudtrail-logs-my-trail:*",
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:vpc-flow-logs:*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": "ec2:DescribeInstances",
      "Resource": "*"
    },
    {
      "Effect": "Allow",
      "Action": "sns:Publish",
      "Resource": "arn:aws:sns:REGION:ACCOUNT-ID:security-correlation-alerts"
    }
  ]
}

Replace REGION, ACCOUNT-ID, and the log-group names with your values. The ec2:DescribeInstances action doesn’t support resource-level permissions, so Resource: "*" is required for that statement; the other statements are scoped to specific ARNs.

To schedule automated runs

Amazon EventBridge (a serverless event bus that connects applications using events) runs targets on a schedule. Create one from the command line, using the role you made earlier.

aws scheduler create-schedule \
  --name s3-access-correlation-hourly \
  --schedule-expression "rate(1 hour)" \
  --target "Arn=arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction,RoleArn=arn:aws:iam::ACCOUNT-ID:role/EventBridgeSchedulerRole" \
  --flexible-time-window "Mode=OFF"

Step 6: Add enrichment context (optional)

Enrichment cuts triage time by adding an independent signal, but it isn’t required for the correlation to work. This step adds costs. You pay your geolocation provider for API calls, and the additional Lambda execution time increases your Lambda charges. To add IP geolocation, sign up for a geolocation API, add this function to the code, and call it where the handler resolves an IP.

import urllib.request
import json

def geo_context(ip_address):
    """Enrich an IP address with geolocation data from your provider."""
    try:
        url = f"https://your-geolocation-api.example/json/{ip_address}"
        with urllib.request.urlopen(url, timeout=5) as response:
            data = json.load(response)
        return {
            "country": data.get("country_name"),
            "city": data.get("city"),
            "org": data.get("org"),
        }
    except Exception as error:
        logger.warning(f"Geolocation lookup failed for {ip_address}: {error}")
        return None

Inside the handler’s loop, after you resolve ip, append the location to the alert.

            if ip:
                geo = geo_context(ip)
                if geo:
                    message += (
                        f" Source location: {geo['city']}, "
                        f"{geo['country']} ({geo['org']})."
                    )

Step 7: Scale to additional patterns and accounts

As your library grows, move the logic into automated pipelines with EventBridge, Lambda, and AWS Step Functions (a serverless orchestration service that coordinates multiple services into workflows), and surface correlations next to findings in Security Hub. For cross-service correlation at scale, CloudWatch unified data and telemetry capabilities can convert security and compliance data into the OCSF format and let you query sources such as CloudTrail, VPC Flow Logs, and DNS logs from one interface. Security Lake with Athena is a strong option for long-term analysis. Choose the endpoint that fits your retention and query needs.

Figure 3 shows a correlation pipeline built on AWS services including EventBridge, Lambda, Step Functions, and AWS Security Hub. The pipeline runs from data sources through scheduled queries and enrichment to automated response and centralized visibility.
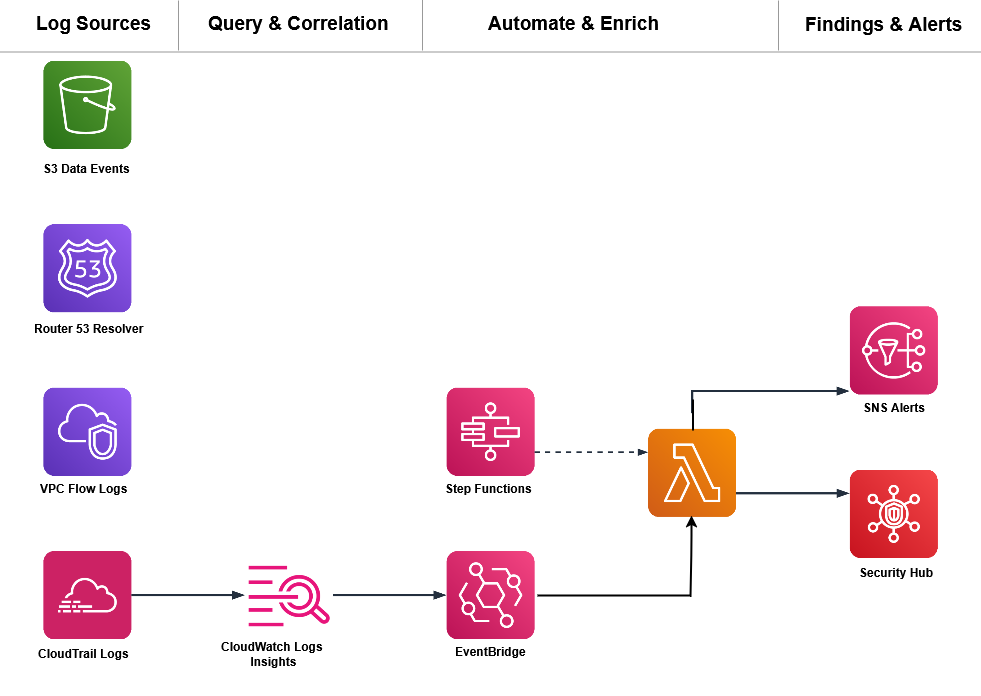
Figure 3: A correlation pipeline built on AWS services

Figure 3: A correlation pipeline built on AWS services

Conclusion

You now have four correlation patterns that layer your business context on top of GuardDuty Extended Threat Detection to catch attacks specific to your environment. A few principles carry across every correlation you build.

  • Identity is your primary correlation key: Track the same principal across services.
  • Time windows matter, but they depend on the attack: Events minutes apart are usually related for fast, automated sequences; the ten-minute bins here work for that pattern. Slow or manual reconnaissance can stretch across hours or days, so widen the window when the pattern is deliberate rather than automated.
  • Context is what you add: Your data classification, access norms, resource ownership, and change windows are signals you bring to detection.
  • Start with one rule: A single well-tuned correlation catches more significant activity than a wall of uncorrelated alerts.

GuardDuty Extended Threat Detection handles the multi-stage patterns common across customers. The correlations in this post add the layer that only your business context can supply. Start with one pattern this week, validate it against your own traffic, and add the next pattern after the first proves reliable.

Have you built correlation rules for patterns not covered here? Share your experience in the Comments section below.

Further reading


Nisha Kashyap

Nisha Kashyap

Nisha Kashyap is a Senior Support Security Engineer at AWS. She works on threat detection and security operations, helping customers investigate security events and build detection that connects signals across AWS services and reflects their own environment.

NaranjaX manages multiple Amazon MSK Serverless clusters in different accounts from their IDP using AWS RAM and Route 53

Post Syndicated from Federico Ostrit original https://aws.amazon.com/blogs/big-data/naranjax-manages-multiple-amazon-msk-serverless-clusters-in-different-accounts-from-their-idp-using-aws-ram-and-route-53/

NaranjaX is a leading fintech platform that aims to simplify and improve the daily financial lives of millions of people in Argentina. Through its digital ecosystem, NaranjaX offers a complete suite of financial products and services, including payments, collections, financing, savings, and protection products.

NaranjaX needed to evolve from their REST-based architecture to an event-driven architecture using Amazon Managed Streaming for Apache Kafka (Amazon MSK) Serverless. In a multi-account environment, MSK Serverless clusters resolve DNS names within their hosting account. AWS published a cross-account connectivity pattern that centralizes clusters in a single account. This is an effective approach for many organizations. NaranjaX required additional flexibility to distribute clusters across accounts while avoiding centralized quota dependencies.

NaranjaX addressed this requirement by developing an approach that uses AWS Resource Access Manager (AWS RAM) and Amazon Route 53 Resolver. In this post, we show you how to expand Amazon MSK Serverless adoption across multiple accounts while maintaining scalability, availability, and reduced operational overhead.

Solution overview

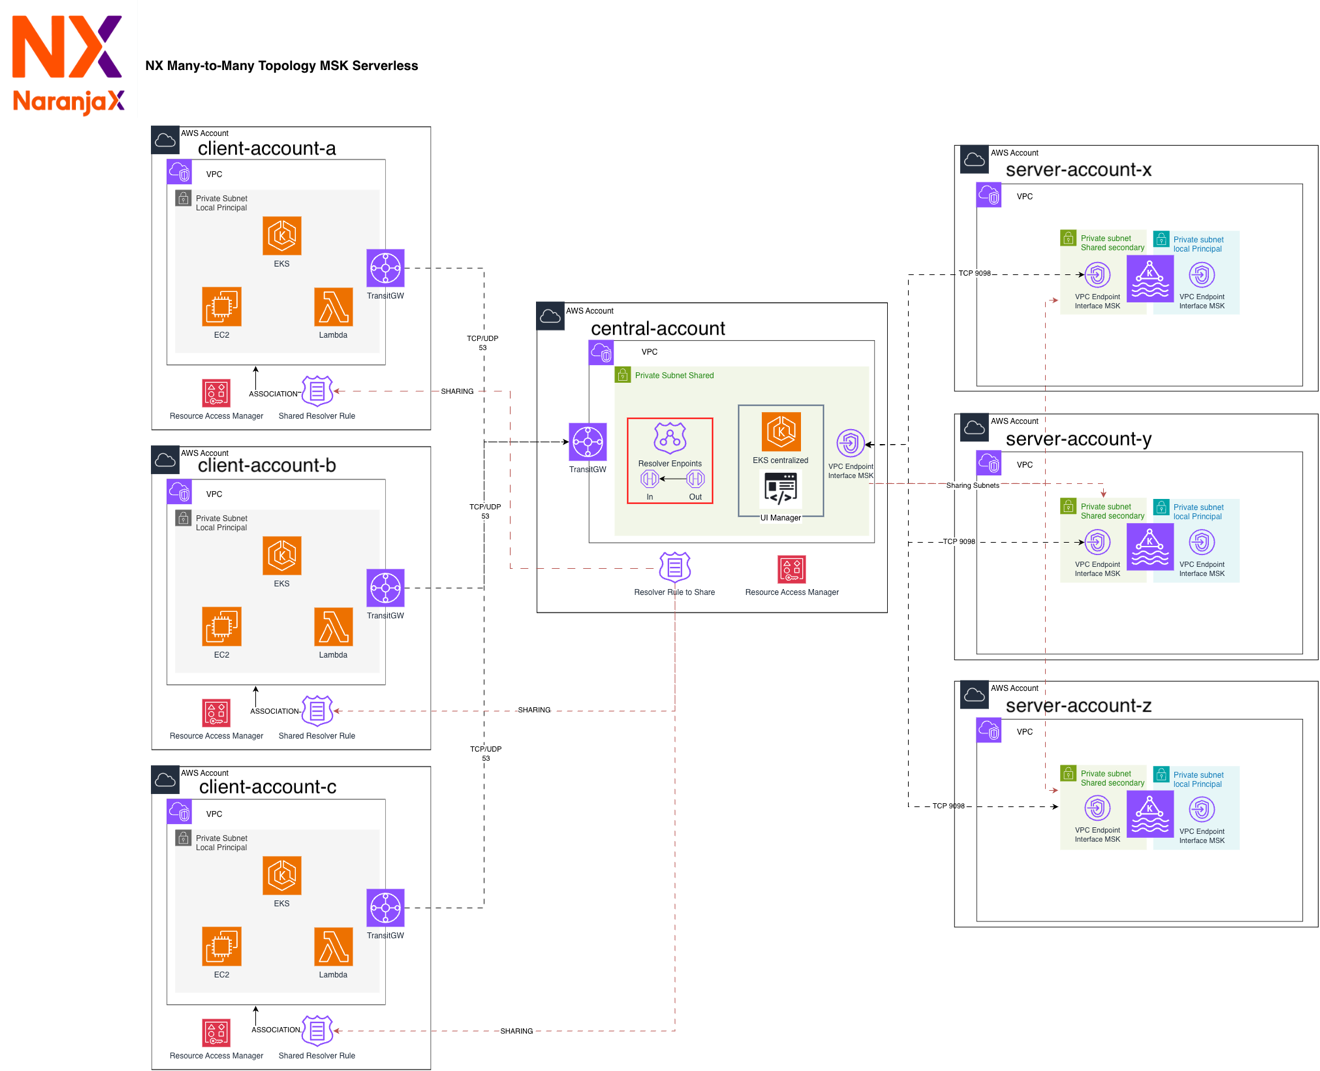
NaranjaX’s solution supports cross-account MSK Serverless deployment through a centralized networking architecture that combines shared virtual private cloud (VPC) resources and DNS resolution capabilities. The solution uses a central AWS account that hosts shared private subnets and Route 53 resolver endpoints, so that MSK Serverless clusters in different accounts can communicate across account boundaries.

The architecture consists of three main components:

  1. A central VPC with private subnets that are shared across accounts using AWS RAM.
  2. Route 53 resolver endpoints and rules that resolve DNS across accounts for MSK Serverless clusters.
  3. Network security configurations that control communication between components.

When an application team creates an MSK Serverless cluster in their account, they can associate it with the shared VPC subnets. The Route 53 resolver rules handle DNS resolution for the cluster’s domain names, while security groups manage access control. This design supports direct connectivity between MSK Serverless clusters and applications across different AWS accounts.

Architecture diagram showing a central account that shares VPC subnets and Route 53 resolver endpoints with application accounts running MSK Serverless clusters

Figure 1: Cross-account architecture with a central networking account sharing subnets and Route 53 resolver endpoints

Implementation requirements and configuration

This section walks you through the steps to configure cross-account MSK Serverless connectivity using shared VPC subnets and Route 53 resolver rules. Before you begin, make sure you have the prerequisites in place.

Prerequisites

Before implementing this solution, confirm the following:

  1. AWS RAM is enabled in your AWS Organization. For instructions, see Enabling resource sharing within AWS Organizations.
  2. Amazon MSK supports shared subnets. When you create an MSK Serverless cluster in any account, you can associate the shared VPC as one of the up to five VPCs supported by the service.
  3. You have a multi-account environment with at least one central networking account and one or more application accounts.
  4. You have permissions to create VPCs, subnets, Route 53 resolver endpoints, and AWS RAM resource shares in the central account.

Step 1: Share subnets with AWS RAM in a central account

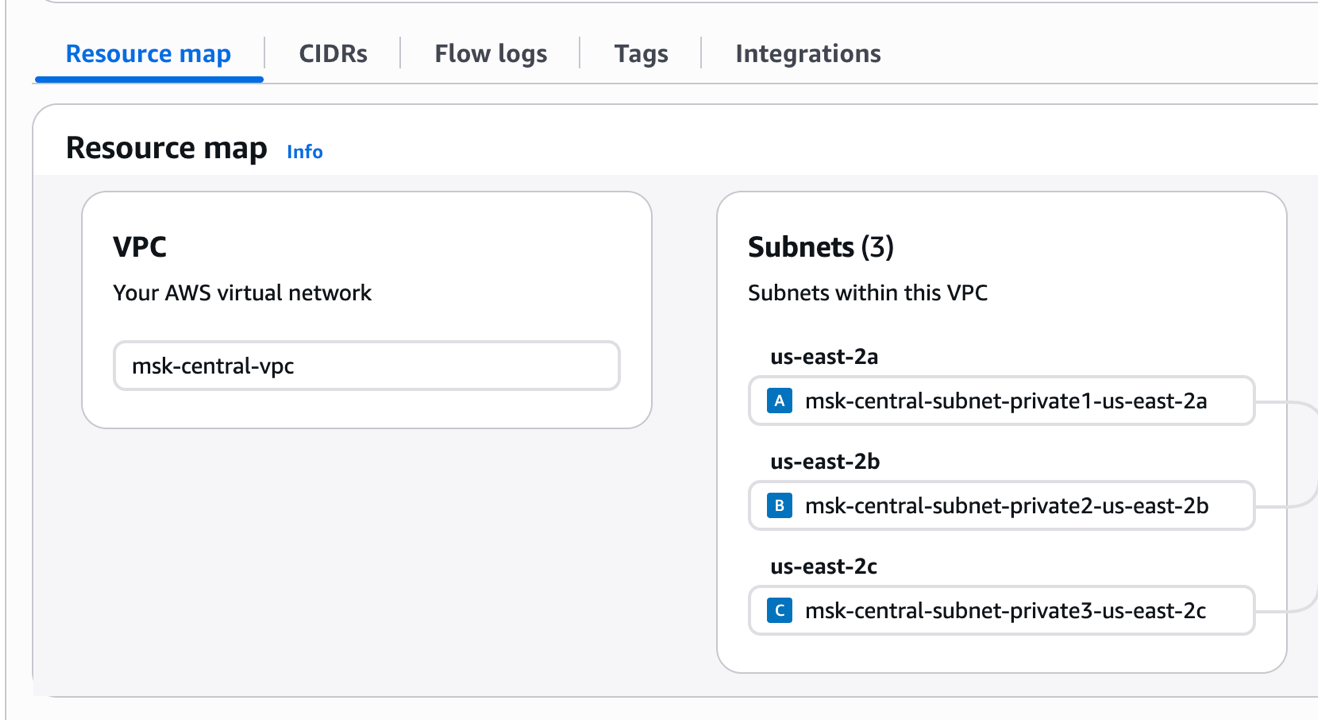
First, create a VPC with private subnets in your central networking account. These subnets are the resources you will share through AWS RAM. For details, see Creating a VPC in the Amazon VPC User Guide.

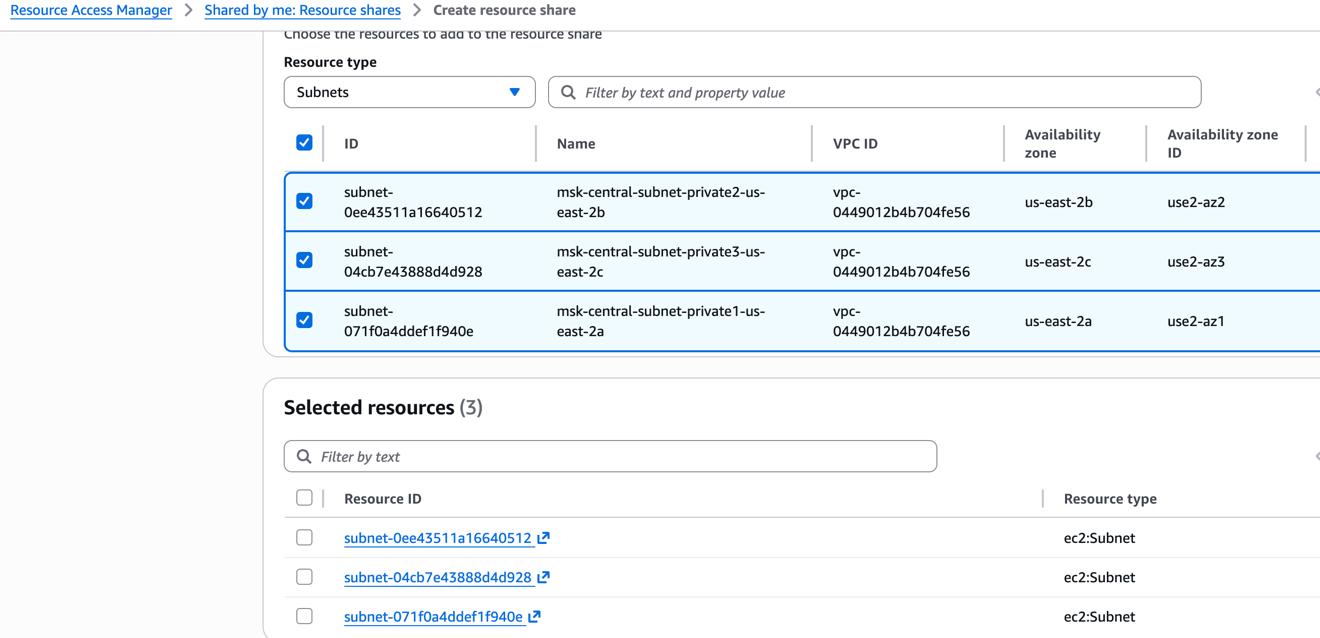
Next, create a resource share for those subnets in AWS RAM. Select the subnets you created and specify the target accounts.

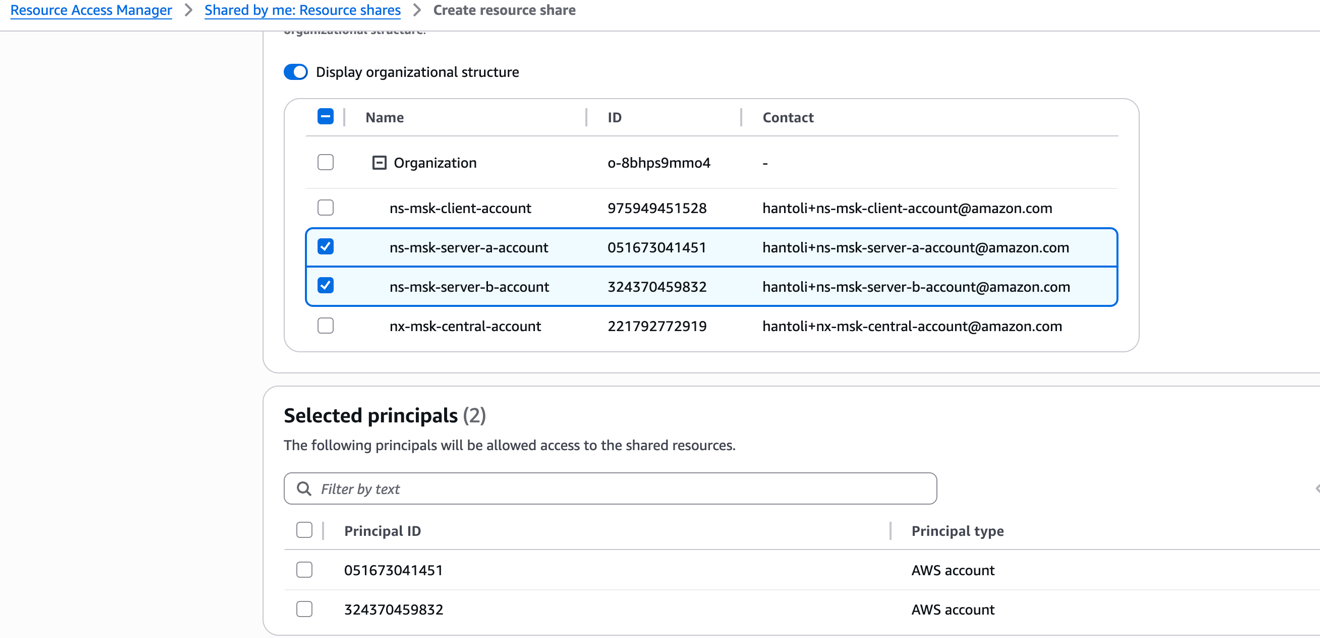
Finally, specify the principals (account IDs) authorized to use the shared subnets. These are the accounts where you will create your Amazon MSK Serverless clusters.

AWS RAM console creating a resource share and selecting the private subnets to share

Figure 2: Creating a resource share for the private subnets in AWS RAM

AWS RAM console specifying the target accounts for the shared subnets

Figure 3: Specifying the target accounts for the resource share

AWS RAM console confirming the principals authorized to use the shared subnets

Figure 4: Confirming the principals authorized to use the shared subnets

Step 2: Configure Amazon Route 53 Resolver rules

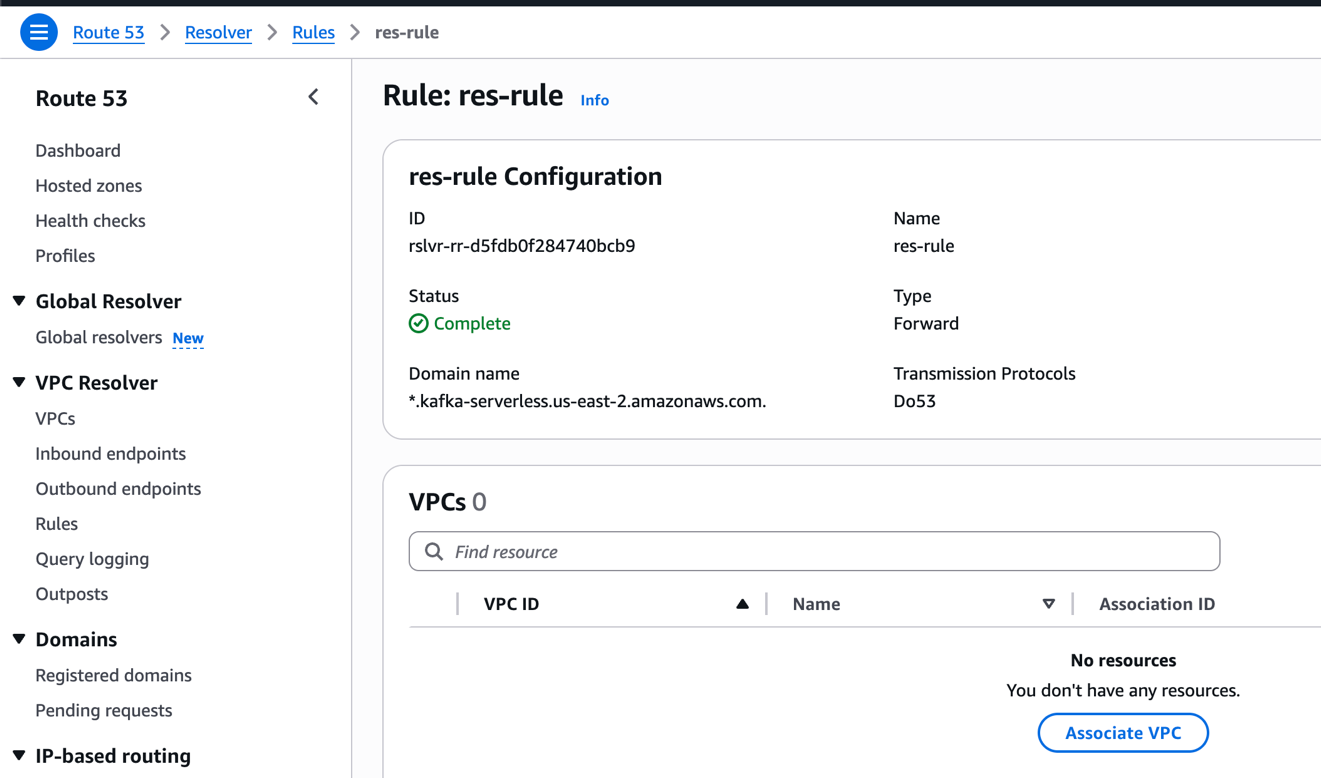
In your central account, create a Route 53 Resolver rule for the domain *.kafka-serverless.<Region>.amazonaws.com. Don’t associate this rule with any VPC at this point.

Amazon Route 53 Resolver rule for the kafka-serverless domain created in the central account

Figure 5: Route 53 Resolver rule for the kafka-serverless domain

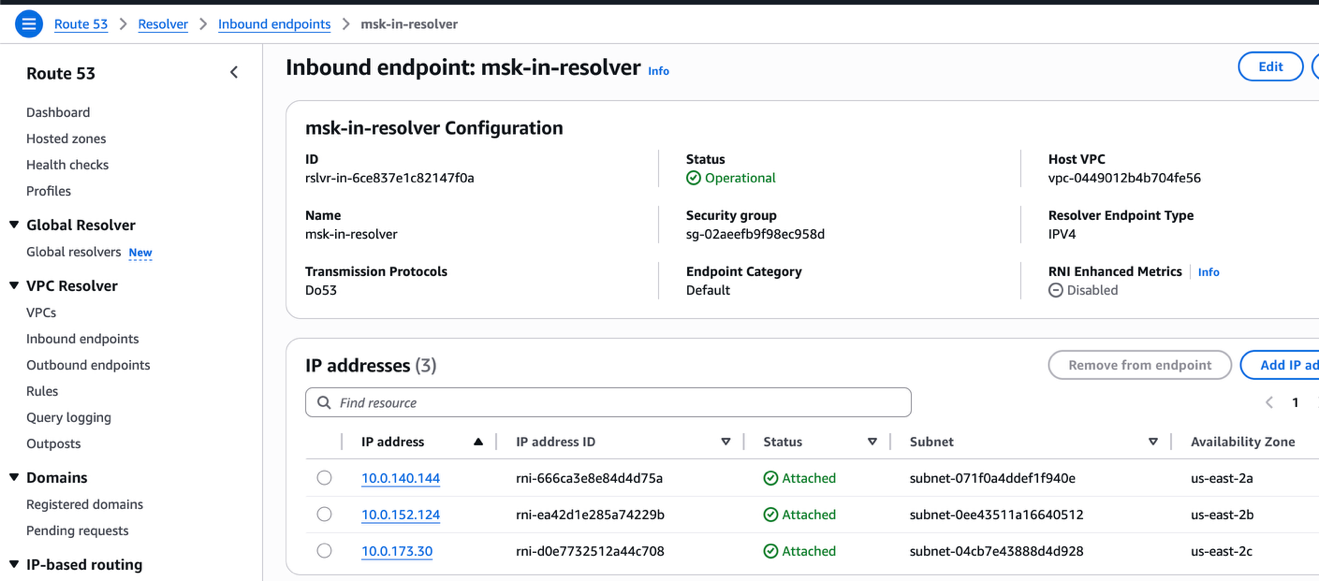
Configure this as a forward rule for the kafka-serverless subdomain. Set up an outbound endpoint in the central account and point the target IP addresses to the inbound endpoint in the same account.

Route 53 Resolver forward rule configuration with an outbound endpoint pointing to the inbound endpoint

Figure 6: Forward rule configuration with outbound and inbound resolver endpoints

Share the resolver rule with your application accounts using AWS RAM so they can resolve the DNS names of their MSK Serverless clusters.

Make sure the central VPC has both inbound and outbound resolver endpoints configured to support cross-account DNS resolution.

Step 3: Configure network security groups

Configure security groups in each consuming account to allow inbound and outbound traffic on port 53 (DNS resolution) and port 9098 (Kafka IAM authentication). This supports both name resolution and secure connectivity to your MSK Serverless brokers across account boundaries.

Step 4: Enable and test many-to-many connectivity

With the networking infrastructure in place, you can now create MSK Serverless clusters in any of your application accounts. To do this, create an MSK Serverless cluster in your application account and associate it with the shared VPC subnets from the central account. The Route 53 resolver rules automatically handle DNS resolution for the cluster endpoints, and the security groups you configured control access. This eliminates the restriction of hosting all clusters in a single account.

You have flexibility in how you configure DNS resolution for your clients. For example, in a client account, you can associate the shared resolver rule with a VPC directly, or you can use the inbound endpoint IP addresses from the central account as custom DNS servers. Configure these either in per-connection scripts or in DHCP option sets for a separate VPC.

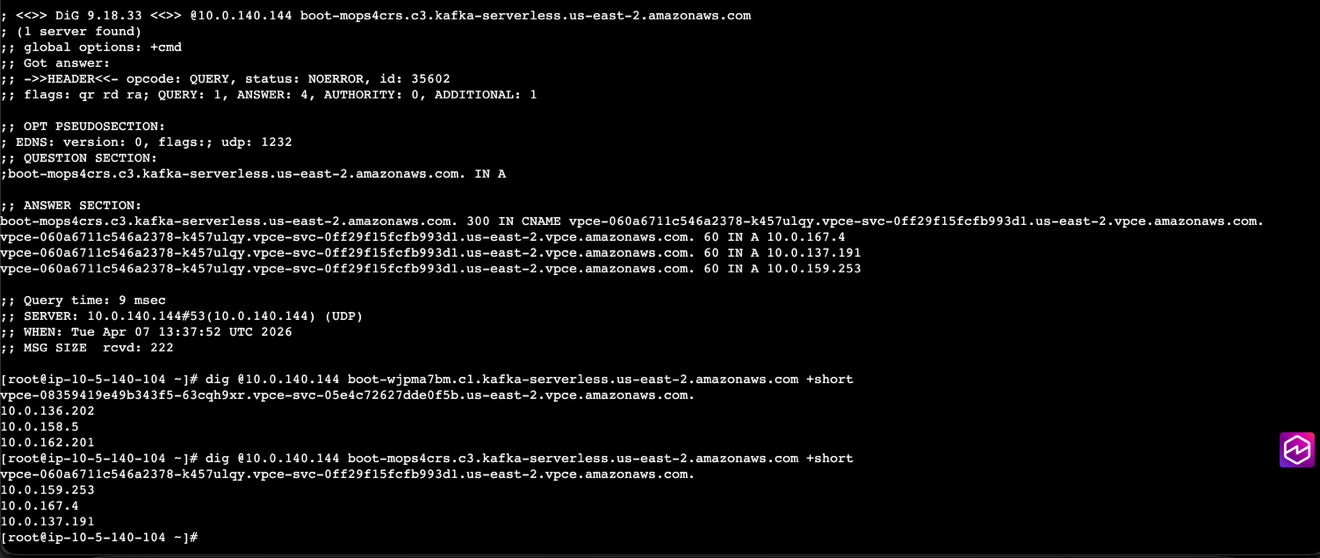
To verify connectivity, use the dig command from an instance in a client account VPC to test DNS resolution of MSK Serverless bootstrap strings across different accounts. The following example uses the +short flag for clarity:
Terminal output of the dig command resolving two MSK Serverless bootstrap strings to broker IP addresses across accounts

Figure 7: The dig command resolving MSK Serverless bootstrap strings across accounts

The output shows that two MSK Serverless clusters (bootstrap strings starting with boot-*) in different accounts and VPCs resolve to the actual IP addresses of the three brokers listening for connections.

This confirms that the architecture supports scalable, consistent cross-account communication for event-driven workloads.

Key benefits

NaranjaX’s implementation of MSK Serverless as its integration backbone delivered measurable advantages across 15+ application teams and over 40 AWS accounts, transforming application development and operations.

Scalability with optimized cost

With MSK Serverless, teams can scale workloads automatically without managing broker capacity. Combined with AWS RAM and Route 53, the architecture supports growth across over 40 accounts while maintaining cost efficiency. By removing the need for dedicated Kafka operations staff and self-managed clusters, NaranjaX reduced infrastructure management costs by approximately 40 percent compared to their previous self-managed Kafka deployment.

Simplified governance and security

Centralized DNS management and VPC sharing keep configurations standardized across all accounts. IAM-based access control, integrated with KATHU, provides clear visibility into topic ownership and consumer access, reducing security review cycles from days to hours.

Faster developer onboarding through IDP integration

By integrating Kafka control-plane operations directly into their internal developer platform (IDP), teams can provision clusters and topics through Terraform modules or a graphical interface. This reduced onboarding time for new teams adopting event-driven architecture from weeks to less than one day.

Reduced operational overhead

Application teams can focus on delivering business features rather than managing Kafka infrastructure. Central operations handle DNS, networking, and resource sharing, while MSK Serverless abstracts broker administration. This reduced operational tickets related to Kafka by over 70 percent and freed the platform team to focus on higher-value initiatives.

Next steps

NaranjaX is evaluating extending this solution by incorporating automatic topic replication across accounts using MSK Replicator, so that certain topics can be exposed as Enterprise Topics in a central hub for global consumption. This will further simplify the architecture, improve data resiliency, and enhance visibility across event domains.

Conclusion

Through this architecture, NaranjaX successfully implemented a many-to-many connectivity model for Amazon MSK Serverless across more than 20 AWS accounts. By using AWS RAM and Amazon Route 53 Resolver, the organization achieved a scalable, secure, and centralized network topology that accelerates the adoption of event-driven architecture without operational bottlenecks. This approach complements the cross-account connectivity pattern published by Tamer Soliman, and provides additional flexibility for organizations that require distributed Kafka clusters in large-scale multi-account environments. To get started, see the Amazon MSK documentation and try this approach in your own multi-account environment.


About the authors

Federico Ostrit

Federico Ostrit

Federico is a Staff Engineer at NaranjaX, where he designs and evolves cloud-native platforms on AWS. He specializes in event-driven architectures, Kubernetes, and distributed systems, helping engineering teams build scalable, resilient, and secure solutions.

Hernan Antolini

Hernan Antolini

Hernan is a Senior Solutions Architect at AWS. He works with FSI customers like NaranjaX in the design of solutions in AWS. He has almost 30 years of experience in IT infrastructure and more than 6 years working in AWS.

Prevent data exfiltration: AWS egress controls for cloud workloads

Post Syndicated from Meriem SMACHE original https://aws.amazon.com/blogs/security/prevent-data-exfiltration-aws-egress-controls-for-cloud-workloads/

When securing an Amazon Web Services (AWS) environment, teams naturally prioritize inbound controls, firewalls, WAFs, and access policies, because that’s where the most visible threats originate. Outbound traffic, on the other hand, tends to get less attention. It’s often left open by default to avoid breaking application dependencies and because the risk feels less immediate. But overlooking egress means missing a key layer of defense. Without visibility into what’s leaving your network, it’s harder to detect unintended data flows, whether from misconfigured services, overly broad permissions, or workloads with unauthorized access.

Real-world incidents highlight why egress controls deserve attention across both traditional cloud workloads and emerging AI-driven architectures.

In traditional cloud environments, application-level security issues remain a persistent threat. For example, when CVE-2025-55182 (React2Shell) was publicly disclosed in December 2025, multiple organized groups began exploitation attempts within hours, targeting unpatched React Server Components to achieve remote code execution. After a workload is accessed by an unauthorized party, they typically establish outbound command-and-control channels and begin exfiltrating data. Without egress controls in place, that outbound traffic can flow freely, and the unauthorized access might go unnoticed until a compliance audit, customer complaint, or incident notification forces discovery.

Agentic AI systems introduce a new dimension to this risk. The OWASP Top 10 for Agentic Applications identifies threats such as Agent Goal Hijack (ASI01), where unauthorized parties manipulate an autonomous agent’s objectives to silently exfiltrate data, and Unexpected Code Execution (ASI05), where an agent with unauthorized access generates and runs potentially damaging code that establishes reverse shells or transfers sensitive data to external endpoints. As organizations deploy AI agents with access to tools, APIs, and code interpreters, these agents become high-value targets, and their outbound network activity must be constrained with the same rigor as any other workload.

In both scenarios, the common thread is unauthorized outbound traffic. In this post, we show you how to implement layered egress detection and protection using AWS services working together to reduce unauthorized data transfer risk, whether the source is an application with unauthorized access or a manipulated AI agent.

Architecture overview

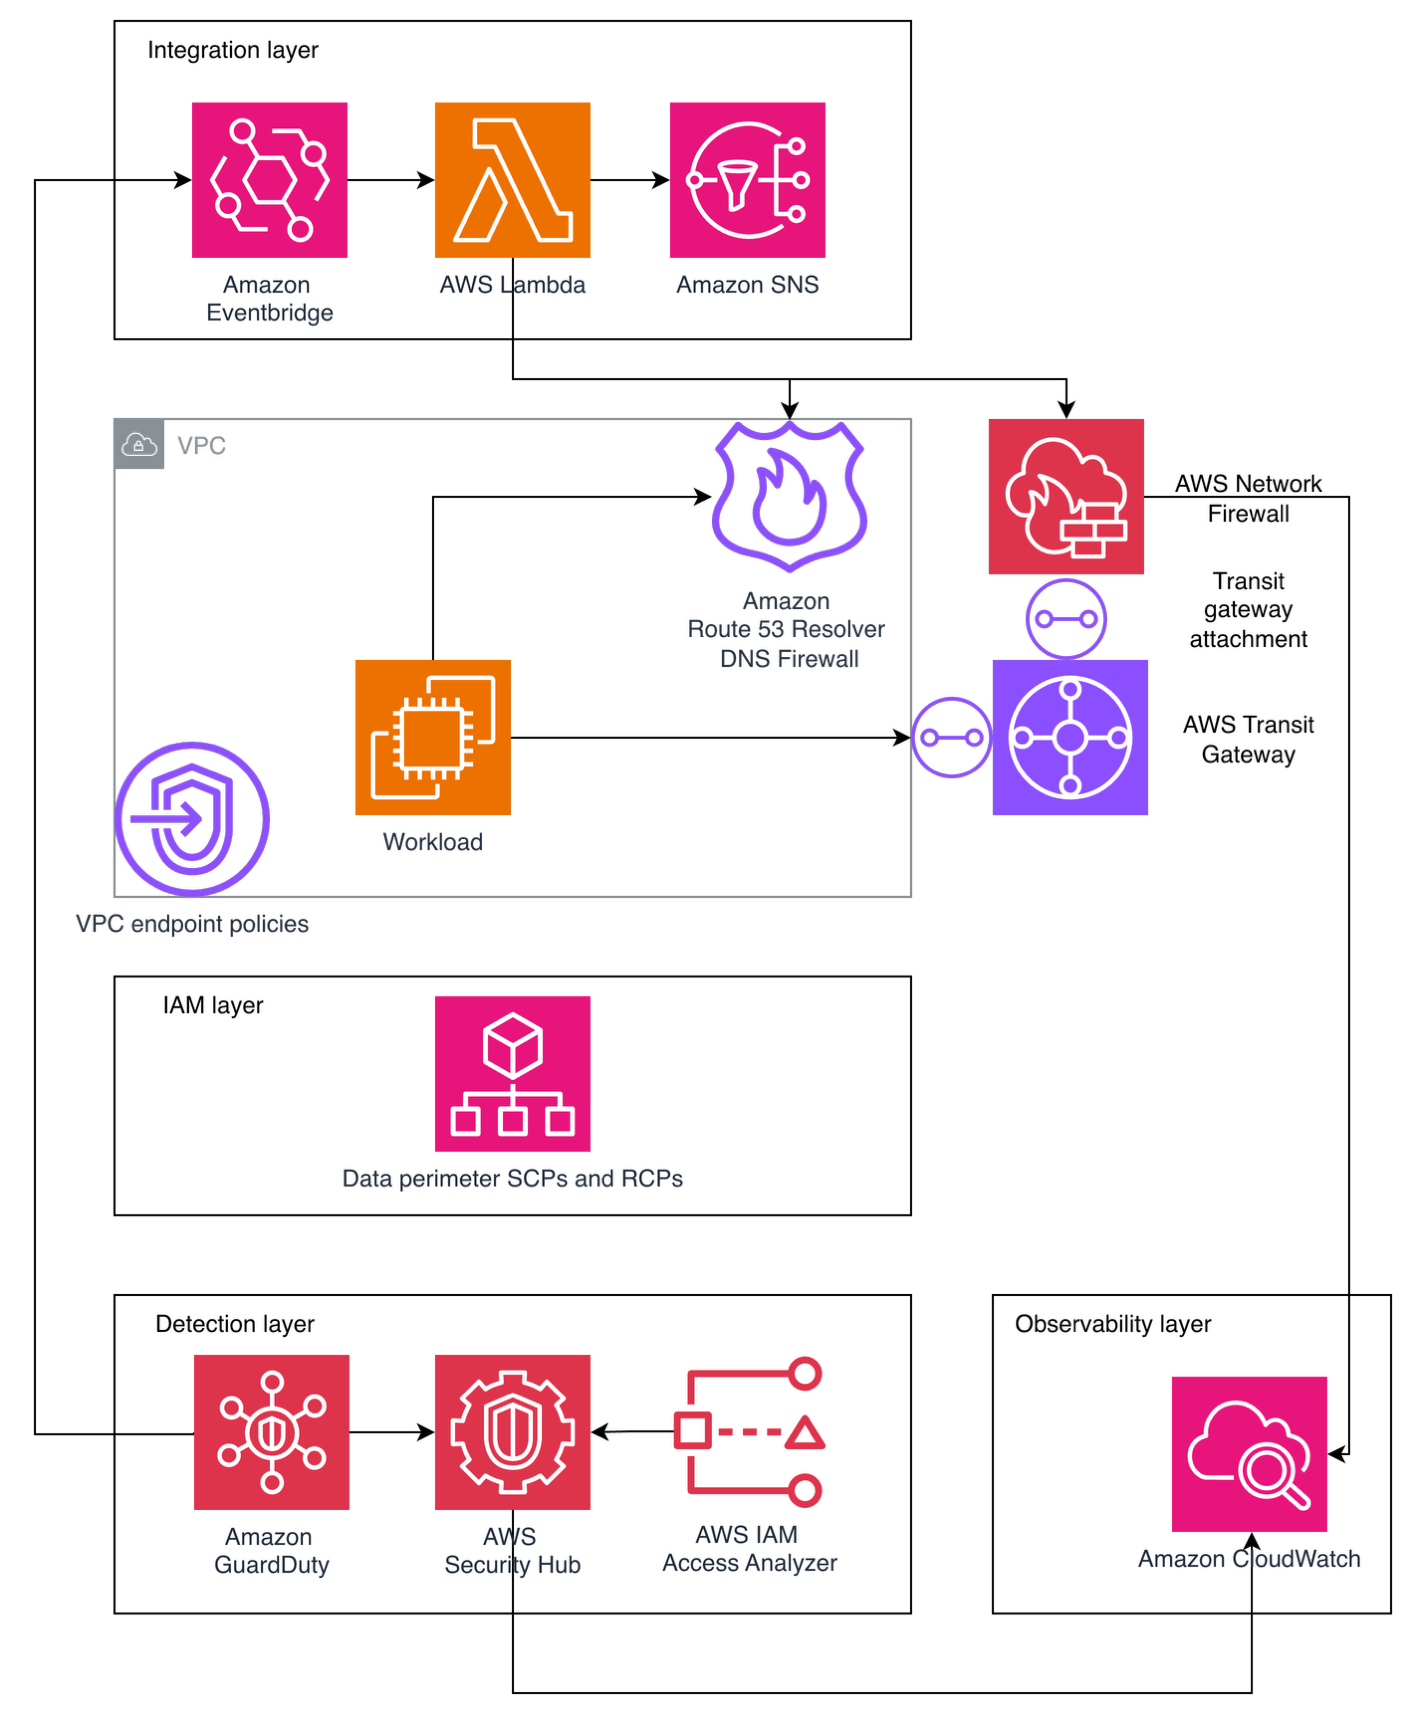
Figure 1: Hub-and-spoke egress control architecture

Figure 1: Hub-and-spoke egress control architecture

The following architecture, shown in Figure 1, illustrates one approach to implementing a hub-and-spoke network pattern for a multi-account AWS environment. Note that alternative designs might be appropriate depending on your organizational requirements and constraints.

Application workloads reside in spoke virtual private clouds (VPCs) that connect to an AWS Transit Gateway, which serves as the central hub for routing inter-VPC and internet-bound traffic while enforcing network segmentation through carefully crafted route tables. Spoke VPCs use VPC endpoints for secure AWS service access, keeping traffic within the AWS network where possible. VPC endpoint policies are applied as key data perimeter controls, restricting which principals can access AWS services and which resources can be accessed through these endpoints.

Internet-bound traffic is routed through a transit gateway-attached AWS Network Firewall, which inspects and filters outbound flows before they reach the internet. This centralized routing model scales horizontally by adding spoke VPCs without modifying the inspection infrastructure, making it well suited for organizations that have multiple AWS accounts.

It’s important to understand that Amazon Route 53 Resolver DNS Firewall must be deployed across your VPCs to filter DNS queries that resolve through the Route 53 VPC Resolver. (DNS queries sent directly to other DNS resolvers bypass it, but can be filtered with AWS Network Firewall.) The DNS firewall uses both managed and custom domain lists to filter DNS queries, blocking resolution of known unauthorized domains before any network connection is established.
Data perimeter controls are enforced at multiple layers: service control policies (SCPs) and resource control policies (RCPs) at the AWS Organizations level, VPC endpoint policies at the network level, and resource policies on individual services. AWS IAM Access Analyzer is deployed at the organization level to continuously detect publicly accessible or externally shared resources.

A detection layer comprising Amazon GuardDuty, AWS Security Hub, and IAM Access Analyzer provides continuous monitoring and threat detection. Findings are routed through an integration layer using Amazon EventBridge, which triggers AWS Lambda-based automated remediation and sends notifications using Amazon Simple Notification Service (Amazon SNS). This integration layer also feeds back into your network controls, automatically updating Network Firewall deny rules and DNS Firewall block lists based on detected threats.

Centralized observability is achieved through Amazon CloudWatch Logs and CloudWatch dashboards. Network Firewall flow logs and alert logs are collected centrally to support incident investigation and compliance reporting.

This architecture applies equally to traditional application workloads and AI-driven workloads. An AI agent running on Amazon Bedrock, for example, typically sits inside a spoke VPC. When that agent invokes an external API or attempts to reach the internet, its traffic follows the same path through Transit Gateway and Network Firewall as any Amazon Elastic Compute Cloud (Amazon EC2) or container workload. The agent doesn’t get a special lane out, it’s subject to the same domain allow-lists, the same DNS filtering, and the same data perimeter policies.

That said, agents often need outbound access to invoke external tools or third-party APIs as part of their normal operation, which makes allow-list design more nuanced. You will want to scope allowing domains tightly to the specific endpoints your agents legitimately need, rather than opening broad categories. Complementing these network-layer controls with application-layer guardrails such as Amazon Bedrock Guardrails—which can filter harmful content and detect prompt attacks before they reach the network layer—adds another layer of defense.

Preventive controls

The following preventive controls block data exfiltration before it occurs. Because they actively disrupt traffic, reserve them for activity that is confirmed or highly likely to be potentially damaging.

AWS Network Firewall

Consider this scenario: an unauthorized party compromises an EC2 instance in one of your spoke VPCs and attempts to exfiltrate sensitive data to an external server. Now consider an agentic AI scenario: an unauthorized party uses prompt injection to hijack an AI agent’s goal (OWASP ASI01), redirecting it to exfiltrate training data to an external endpoint. Network Firewall is designed to block this attempt because the unauthorized destination isn’t on the approved domain allow-list—the same control that stops an EC2 instance with unauthorized access— also stops a manipulated AI agent.
Without centralized egress inspection, that traffic flows directly to the internet through a NAT gateway. Network Firewall prevents this by providing centralized, Layers 3–7 deep packet inspection with advanced threat intelligence capabilities, including IP address, port, and protocol filtering; plus packet content inspection using Suricata-compatible rules.

In this architecture, Transit Gateway funnels internet-bound traffic from multiple spoke VPCs through Network Firewall for centralized inspection. The firewall endpoint becomes the target for 0.0.0.0/0 routes, routing outbound internet traffic for inspection before reaching NAT gateways for address translation. In both scenarios, Network Firewall blocks the exfiltration attempt at the network layer before data leaves your environment. Its key capabilities include:

  • Domain name filtering: Block traffic to unauthorized destinations (such as a command-and-control server at *.untrusted-domain.com)
  • IP and port rules: Define explicit allow-lists for external IPs your applications truly need, blocking everything else
  • Domain category filtering: Block entire categories of domains that your workloads should never communicate with
  • IDS and IPS: Detect and block known attack patterns in outbound traffic using Suricata-compatible rules
  • Port and protocol enforcement: Help ensure only expected protocols use their designated ports (for example, only HTTPS on TCP port 443), preventing protocol tunneling
  • Geographic IP filtering: Block outbound traffic to geographic regions where your organization has no business relationships
  • TLS decryption: Inspect encrypted traffic to detect exfiltration attempts hidden within HTTPS connections
  • Threat intelligence integration: Use managed threat intelligence (such as active threat defense that uses the Amazon threat intelligence system MadPot) feeds or custom Suricata rules to detect unexpected patterns
  • Automatic scaling: Handles up to 100 Gbps per Availability Zone

For multi-account environments, AWS Firewall Manager can centrally deploy and manage Network Firewall across your organization’s accounts, helping maintain consistent egress rules everywhere. Additionally, AWS Network Firewall Proxy (in preview) offers explicit proxy capabilities with granular HTTP/HTTPS filtering—including URL path and HTTP method-level controls—for workloads that require application-layer inspection of outbound web traffic.

Route 53 Resolver DNS Firewall

DNS queries made through Route 53 VPC Resolver don’t pass through the outbound network path inspected by Network Firewall or third-party firewalls. Unauthorized parties can take advantage of this by encoding sensitive data within DNS queries to external servers, a technique known as DNS tunneling. This risk extends to agentic AI workloads. An agent with code execution capabilities (OWASP ASI05) could be tricked into running a script that encodes sensitive data (like customer records, model weights, API keys) into DNS queries directed at an externally controlled nameserver. DNS Firewall is designed to block these queries regardless of whether they originate from a traditional workload or an AI agent, because the filtering happens at the resolver level before any connection is established.

Because DNS traffic is essential for normal operations and often overlooked in security architectures, it represents a common unauthorized data exfiltration channel. Route 53 Resolver DNS Firewall closes this gap by filtering and potentially blocking outbound DNS queries from your VPCs. Its core capabilities consist of:

  • Block unauthorized domains: AWS provides managed domain lists, including an Aggregate Threat List covering malware, ransomware, botnet, spyware, and DNS tunneling
  • Enforce allow-lists: Permit only queries to approved domains, blocking everything else
  • DNS Firewall Advanced features: AI and machine learning (AI/ML)-backed detection of DNS tunneling, Domain Generation Algorithms (DGAs), and dictionary DGAs

Configuration is straightforward: Create rule groups with domain match lists and actions (block, allow, and alert), then associate them with your VPCs. The DNS resolver applies these rules to every DNS query made from instances in the VPC through Route 53 Resolver. This prevents unauthorized parties from using DNS tunneling to exfiltrate data, a technique that completely bypasses inspection by firewalls in the egress VPC.

For a deeper look at the risks associated with DNS exfiltration and DNS Firewall Advanced capabilities, see Protect against advanced DNS threats with Amazon Route 53 Resolver DNS Firewall.

Data perimeters

A data perimeter is a set of preventive guardrails that allow only your trusted identities to access trusted resources from expected networks. While the preceding controls secure the network paths out of your environment, data perimeters secure the API-level paths, helping to ensure that even if an unauthorized party gains access to valid credentials, they can’t use AWS service APIs to move data to resources outside your organization.

This comprehensive approach uses three primary AWS capabilities working together:

  1. Service control policies (SCPs): Organization-wide preventive controls that restrict what identities can do. In the context of egress protection, SCPs can prevent users from creating resources that bypass your egress controls (for example, preventing the creation of VPCs without DNS Firewall associations or blocking the use of services that could establish alternative outbound paths).
  2. Resource control policies (RCPs): Controls that restrict API access to your resources. While RCPs aren’t directly egress controls, they act as a complementary layer. For example, they can block attempts to access your Amazon Simple Storage Service (Amazon S3) buckets from outside your organization at the resource level.
  3. VPC endpoint policies: VPC endpoints enable private communication with AWS services without traffic going through the internet. VPC endpoint policies are resource-based AWS Identity and Access Management (IAM) policies that govern what can be accessed through that endpoint. This is where data perimeters most directly function as an egress control.

Consider the following VPC endpoint policy that restricts Amazon S3 access through the endpoint to only S3 buckets within your organization, directly preventing an insider or a workload with unauthorized access from copying data to an external S3 bucket:

{
  "Statement": [{
    "Sid": "DenyAccessToNonOrgBuckets",
    "Effect": "Deny",
    "Principal": "*",
    "Action": "s3:*",
    "Resource": "*",
    "Condition": {
      "StringNotEqualsIfExists": {
        "aws:ResourceOrgID": "<my-org-id>"
      }
    }
  }]
}

This policy is designed to deny any Amazon S3 operation through this VPC endpoint unless the target S3 bucket belongs to your organization. Without this control, a workload with unauthorized access could use aws s3 cp to copy sensitive data to an externally controlled bucket in a different AWS account.

Data perimeter policies don’t grant new permissions, they narrow what’s accessible by establishing guardrails, acting as a second authorization layer. By implementing these perimeters using IAM condition keys like aws:PrincipalOrgID, aws:ResourceOrgID, aws:SourceVpc, and aws:SourceVpce, you create layered permissions guardrails that help prevent unintended access patterns and configuration errors.

For more information on implementing perimeter controls, explore the Building a Data Perimeter AWS whitepaper.

Detective controls

The following detective controls surface data exfiltration attempts after they occur. Because they observe rather than disrupt traffic, you can apply them broadly to flag unexpected activity for investigation. Use the findings to identify recurring unauthorized patterns that can graduate into preventive controls.

Amazon GuardDuty: Detective control for egress threats

GuardDuty serves as your critical detection layer for egress protection, continuously monitoring for outbound threats that evade or take advantage of your preventive controls. GuardDuty identifies behavioral anomalies and attack patterns that indicate active data exfiltration attempts. Its egress-focused detection capabilities include:

  • DNS-based data exfiltration detection: The Trojan:EC2/DNSDataExfiltration finding alerts when EC2 instances are transferring data through DNS channels. GuardDuty also identifies queries to DGA domains commonly used for command-and-control communication.
  • Known malicious actor detection: Exfiltration:S3/MaliciousIPCaller triggers when Amazon S3 data APIs like GetObject or CopyObject are invoked from IP addresses on AWS threat intelligence feeds, signaling active data extraction attempts.
  • Multi-step attack sequence correlation: GuardDuty Extended Threat Detection correlates multiple unexpected events to identify multi-stage exfiltration campaigns. For example, AttackSequence: S3/CompromisedData detects when unauthorized parties modify S3 bucket policies to broaden access and then systematically extract data using stolen credentials.

GuardDuty findings serve dual purposes in your egress strategy. Alerts about attempted exfiltration that failed confirm your preventive layers (Network Firewall, DNS Firewall, and data perimeters) are functioning effectively: the threat was detected because it progressed far enough to trigger behavioral analysis, but your controls blocked the actual data loss. Conversely, findings indicating successful exfiltration trigger immediate incident response workflows, enabling you to contain active incidents, revoke stolen credentials, and quarantine affected resources before significant damage occurs.

Integrate GuardDuty with Security Hub for centralized correlation across your security services and implement automated response through EventBridge and Lambda functions to enable real-time containment when high-severity exfiltration findings occur.

IAM Access Analyzer

IAM Access Analyzer helps identify potential data exfiltration paths by detecting resources accessible from outside your AWS account or organization. It uses automated reasoning technology to analyze resource-based policies and identify which of your resources can be accessed by external entities (principals outside your zone of trust), continuously monitoring public and cross-account access.

External access analyzers identify resources shared with external principals (such as other AWS accounts or public access). For example, when an S3 bucket is configured to allow access outside your zone of trust through bucket policies, ACLs, or access points, IAM Access Analyzer generates a finding with details about the access path, including the external principal and the level of access granted. Security teams can respond by taking immediate action to remove unintended access or by setting up automated notifications through EventBridge to engage development teams for remediation.

AWS Security Hub

Security Hub exposure findings provide a comprehensive view of potential security risks by correlating data from multiple AWS security services. These findings identify when resources might be vulnerable to data exfiltration by integrating intelligence from GuardDuty (for threat detection), Amazon Inspector (for vulnerability assessment), Security Hub CSPM (for configuration compliance), and Amazon Macie (for sensitive data discovery). For example, it can identify when a publicly exposed S3 bucket contains sensitive data and isn’t encrypted at rest, flagging it as a potential data exfiltration risk that requires immediate attention.

AWS Shield network security director (in preview) complements Security Hub by discovering and analyzing your network topology to identify resources with unrestricted outbound internet access, helping you detect potential egress blind spots across your environment.

Egress security strategy

You don’t need to implement all these controls at once. The following phased approach lets you build your egress security posture incrementally, at a pace that matches your organization’s operational maturity and risk tolerance.

  • Phase 1 – Quick wins: Enable Route 53 DNS Firewall across your VPCs to close the DNS exfiltration gap. Enable GuardDuty across your accounts for baseline threat detection.
  • Phase 2 – Foundational: Deploy organization-wide data perimeters (SCPs, RCPs, and VPC endpoint policies). Deploy Network Firewall as a transit gateway-attached firewall.
  • Phase 3 – Efficient: Enable IAM Access Analyzer for continuous external access detection. Implement automated remediation through EventBridge and Lambda to update firewall rules in real time. Centralize findings in Security Hub with automated alerting.

Conclusion

Egress security isn’t a single control—it’s a layered strategy. Start by assessing your current posture across network filtering, DNS security, data perimeters, and detective controls. Identify the gaps, then follow the phased approach outlined in this post to close them incrementally. Regular testing through simulated exfiltration attempts validates that your controls work effectively. These controls apply with equal force to agentic AI workloads, where manipulated agents can become unintended exfiltration vectors. Put egress under control and turn your outbound blind spots into monitored checkpoints.

If you have feedback about this post, submit comments in the Comments section below.


Merriem-SMACHE

Meriem SMACHE

Meriem is a Security Specialist Solutions Architect at AWS, supporting customers in the design and deployment of resilient cloud and AI solutions, from generative AI workloads to fully autonomous agentic systems, that meet their regulatory requirements and security needs.

Maxim Raya

Maxim Raya

Maxim is a Security Specialist Solutions Architect at AWS. In this role, he helps clients accelerate their cloud transformation by increasing their confidence in the security and compliance of their AWS environments.

Threat tactic spotlight: Subdomain takeover

Post Syndicated from Matt Gurr original https://aws.amazon.com/blogs/security/threat-tactic-spotlight-subdomain-takeover/

In this blog post you’ll learn how to detect and prevent subdomain takeover – a tactic where threat actors exploit dangling DNS records to redirect traffic to attacker-controlled resources. We’ll explain the issue, how the situation arises, and how you can use various AWS features and services to help mitigate the impact of this tactic.

Under the shared responsibility model, securing configurations in the cloud is your responsibility. AWS supports you through strong defaults, guidance in the Security Pillar of the Well-Architected Framework, and security services to help you meet that responsibility. The AWS Customer Incident Response Team (AWS CIRT) also monitors for new and trending tactics that threat actors use to exploit specific customer configurations, so that you can make informed design decisions and improve your response plans.

AWS CIRT has observed threat actors actively scanning for public DNS CNAME records that point to resources that no longer exist, looking for subdomain takeover opportunities.

Note: The subdomain takeover tactic does not leverage vulnerabilities of AWS services. It exploits a dangling DNS record to redirect traffic to an attacker-controlled resource.

Quick DNS Primer

CNAME Records: A CNAME (Canonical Name) record is a DNS entry that points one domain name to another. For example, api.example.com can be configured to point to api.example.s3-website-us-east-1.amazonaws.com. This feature of DNS enables users to configure a memorable, human-friendly domain name while the actual resource lives at a longer, machine-generated AWS hostname. A security issue emerges when the target resource is deleted but the CNAME record pointing to it remains – creating a “dangling” record.

Dangling Records: When a resource (like an S3 bucket) is deleted but the DNS record pointing to it is left behind, that DNS record becomes “dangling”, pointing to a resource that no longer exists. For resources in globally shared namespaces, threat actors can potentially reclaim the name of your deleted resource and serve malicious content through your DNS record.

What is subdomain takeover?

A subdomain is a prefix added to a domain that allows you to organize access to your resources. A subdomain takeover occurs when you delete the underlying resource and a threat actor creates a new resource with the same name to take advantage of the DNS records still pointing to it.

A subdomain takeover is possible when a CNAME record points to an AWS resource that uses a globally shared DNS namespace where the resource name can be chosen by any AWS customer. The following AWS resources meet these criteria:

Amazon S3 (global namespace): Bucket names like mybucket.s3.amazonaws.com are globally unique and can be claimed by any account if the bucket is deleted. Note: S3 buckets created with account regional namespaces (launched March 2026) are scoped to your account and are not subject to this issue.

Amazon CloudFront: Distribution domain names like d111111abcdef8.cloudfront.net are assigned by AWS and cannot be chosen by an attacker. However, if you delete a distribution and another customer creates one that happens to receive the same domain name, a dangling CNAME could resolve to their content.

AWS Elastic Beanstalk: Environment names like myapp.elasticbeanstalk.com are globally unique and can be claimed by any account if the environment is terminated.

Resources like Amazon VPC, Amazon EC2 instances, or private hosted zones are not subject to this tactic because they do not expose globally claimable DNS namespaces.

MITRE ATT&CK classifies this technique under T1584.001: Compromise Infrastructure – Domains.

Analyzing an example scenario

Consider the following scenario:

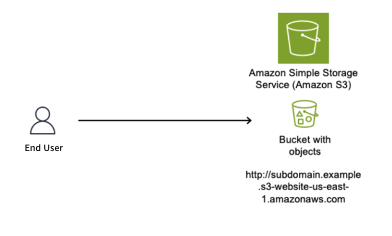
You create a DNS CNAME record pointing to your S3 website endpoint. The subdomain subdomain.example.com now resolves to subdomain.example.s3-website-us-east-1.amazonaws.com, which serves content from the S3 bucket named subdomain.example. If your team deletes the bucket and forgets to delete the DNS record, users that navigate to the site will see an error stating that the bucket doesn’t exist. However, at this point, if a threat actor sees this error and moves in to claim the bucket name, they will be able to set up their own site that users will see when they navigate to the subdomain.example.com site.

Figure 1 shows an S3 bucket named subdomain.example (a globally unique bucket name) configured to host a static website, with the S3 website endpoint subdomain.example.s3-website-us-east-1.amazonaws.com.

Figure 1: S3 bucket configured as a static website

Figure 1: S3 bucket configured as a static website

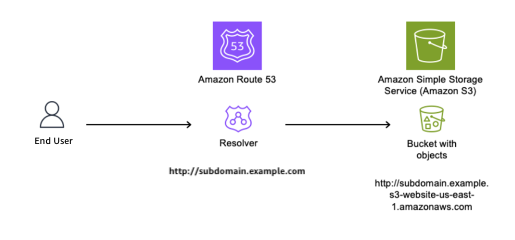
As shown in Figure 2, we use Amazon Route 53 to create a CNAME record to resolve to our Amazon domain name; to give users a friendly name and so they do not have to remember the long S3 website name in URLs.

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

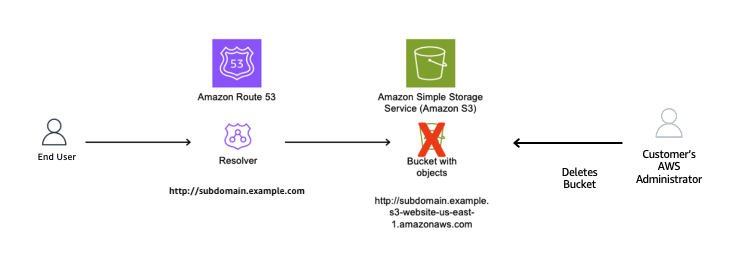
The customer’s AWS administrator decides to stop serving content from the S3 bucket and deletes it, as shown in Figure 3.

Figure 3: Resource deleted without removing the CNAME record

Figure 3: Resource deleted without removing the CNAME record

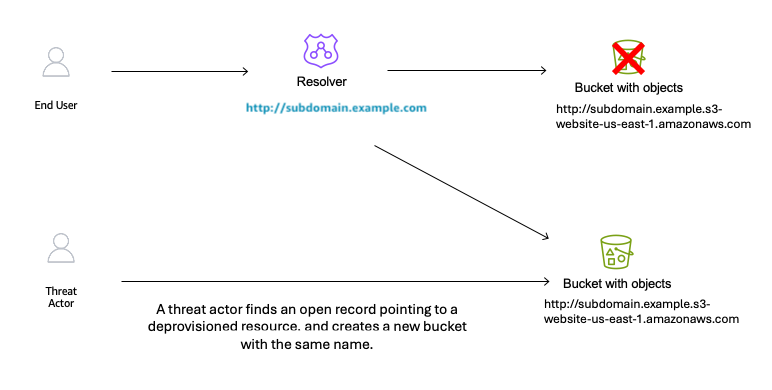
With the S3 bucket deleted and the CNAME record still in place, the DNS record is now dangling. A threat actor identifies this situation and creates a new S3 bucket with the same global name subdomain.example in an AWS account that the threat actor controls, as shown in Figure 4. The threat actor can now serve content from this new bucket, including potentially malicious content. End users remain unaware of this switch and continue to access subdomain.example.com, trusting the content because it appears to originate from a URL they recognize.

Figure 4: Subdomain takeover happens

Figure 4: Subdomain takeover happens

Potential impacts of a sub-domain takeover

Consider these potential impacts:

Reputation risk: There is a potential risk to your organization’s reputation, because you don’t control the content being served from the threat actor’s site that your DNS record points to.

Potential exposure to phishing campaigns: Users within your organization might have the subdomain bookmarked in their browser, not knowing the resource is no longer available, then unsuspectingly navigate to the site that now hosts malware or is used to phish user credentials.

Blocking: If the subdomain is flagged by security vendors for malicious activity, it could impact your business operations.

Financial loss: Subdomain takeover incidents can result in a financial impact due to the potential disruption to service delivery as you deal with the event.

Proactive detection

AWS Config for proactive detection

For proactive detection, you can use AWS Config to continuously monitor your Route 53 CNAME records and verify that the target resources exist in your account.

Prerequisite: This approach requires AWS Config recorder to be enabled for the resource types you want to monitor (S3 buckets, CloudFront distributions, Elastic Beanstalk environments). If Config isn’t recording a resource type, it won’t appear in the inventory check. For more information, see Setting up AWS Config with the console.

Why use AWS Config inventory instead of DNS resolution checks?

A common approach is to check whether a CNAME resolves to a valid endpoint. However, this method has a critical flaw: if an attacker has already claimed the resource, DNS resolution will succeed – to their resource, not yours. You would have no indication that you don’t own what’s responding.

By querying AWS Config’s recorded configuration items, you’re checking whether the resource exists in your account inventory, not just whether something responds at that DNS name. This approach correctly identifies dangling CNAMEs even after a takeover has occurred.

Implementation approach:

Account-level vs. organization-level scope

The reference implementation queries AWS Config inventory within a single account. This means that if a CNAME record in Account A points to a resource that legitimately exists in Account B within the same AWS organization, the rule will flag it as NON_COMPLIANT.

For organizations that share resources across accounts, you can modify the solution to use an AWS Config Aggregator, which queries resource inventory across all accounts in your organization. This is similar to how IAM Access Analyzer supports both account-level and organization-level scopes. To use this approach, you need an organization-level Config Aggregator already configured, and the Lambda function’s IAM role needs the config:SelectAggregateResourceConfig permission.

We recommend starting with account-level scope for simplicity, then expanding to organization-level if your environment includes cross-account resource sharing.

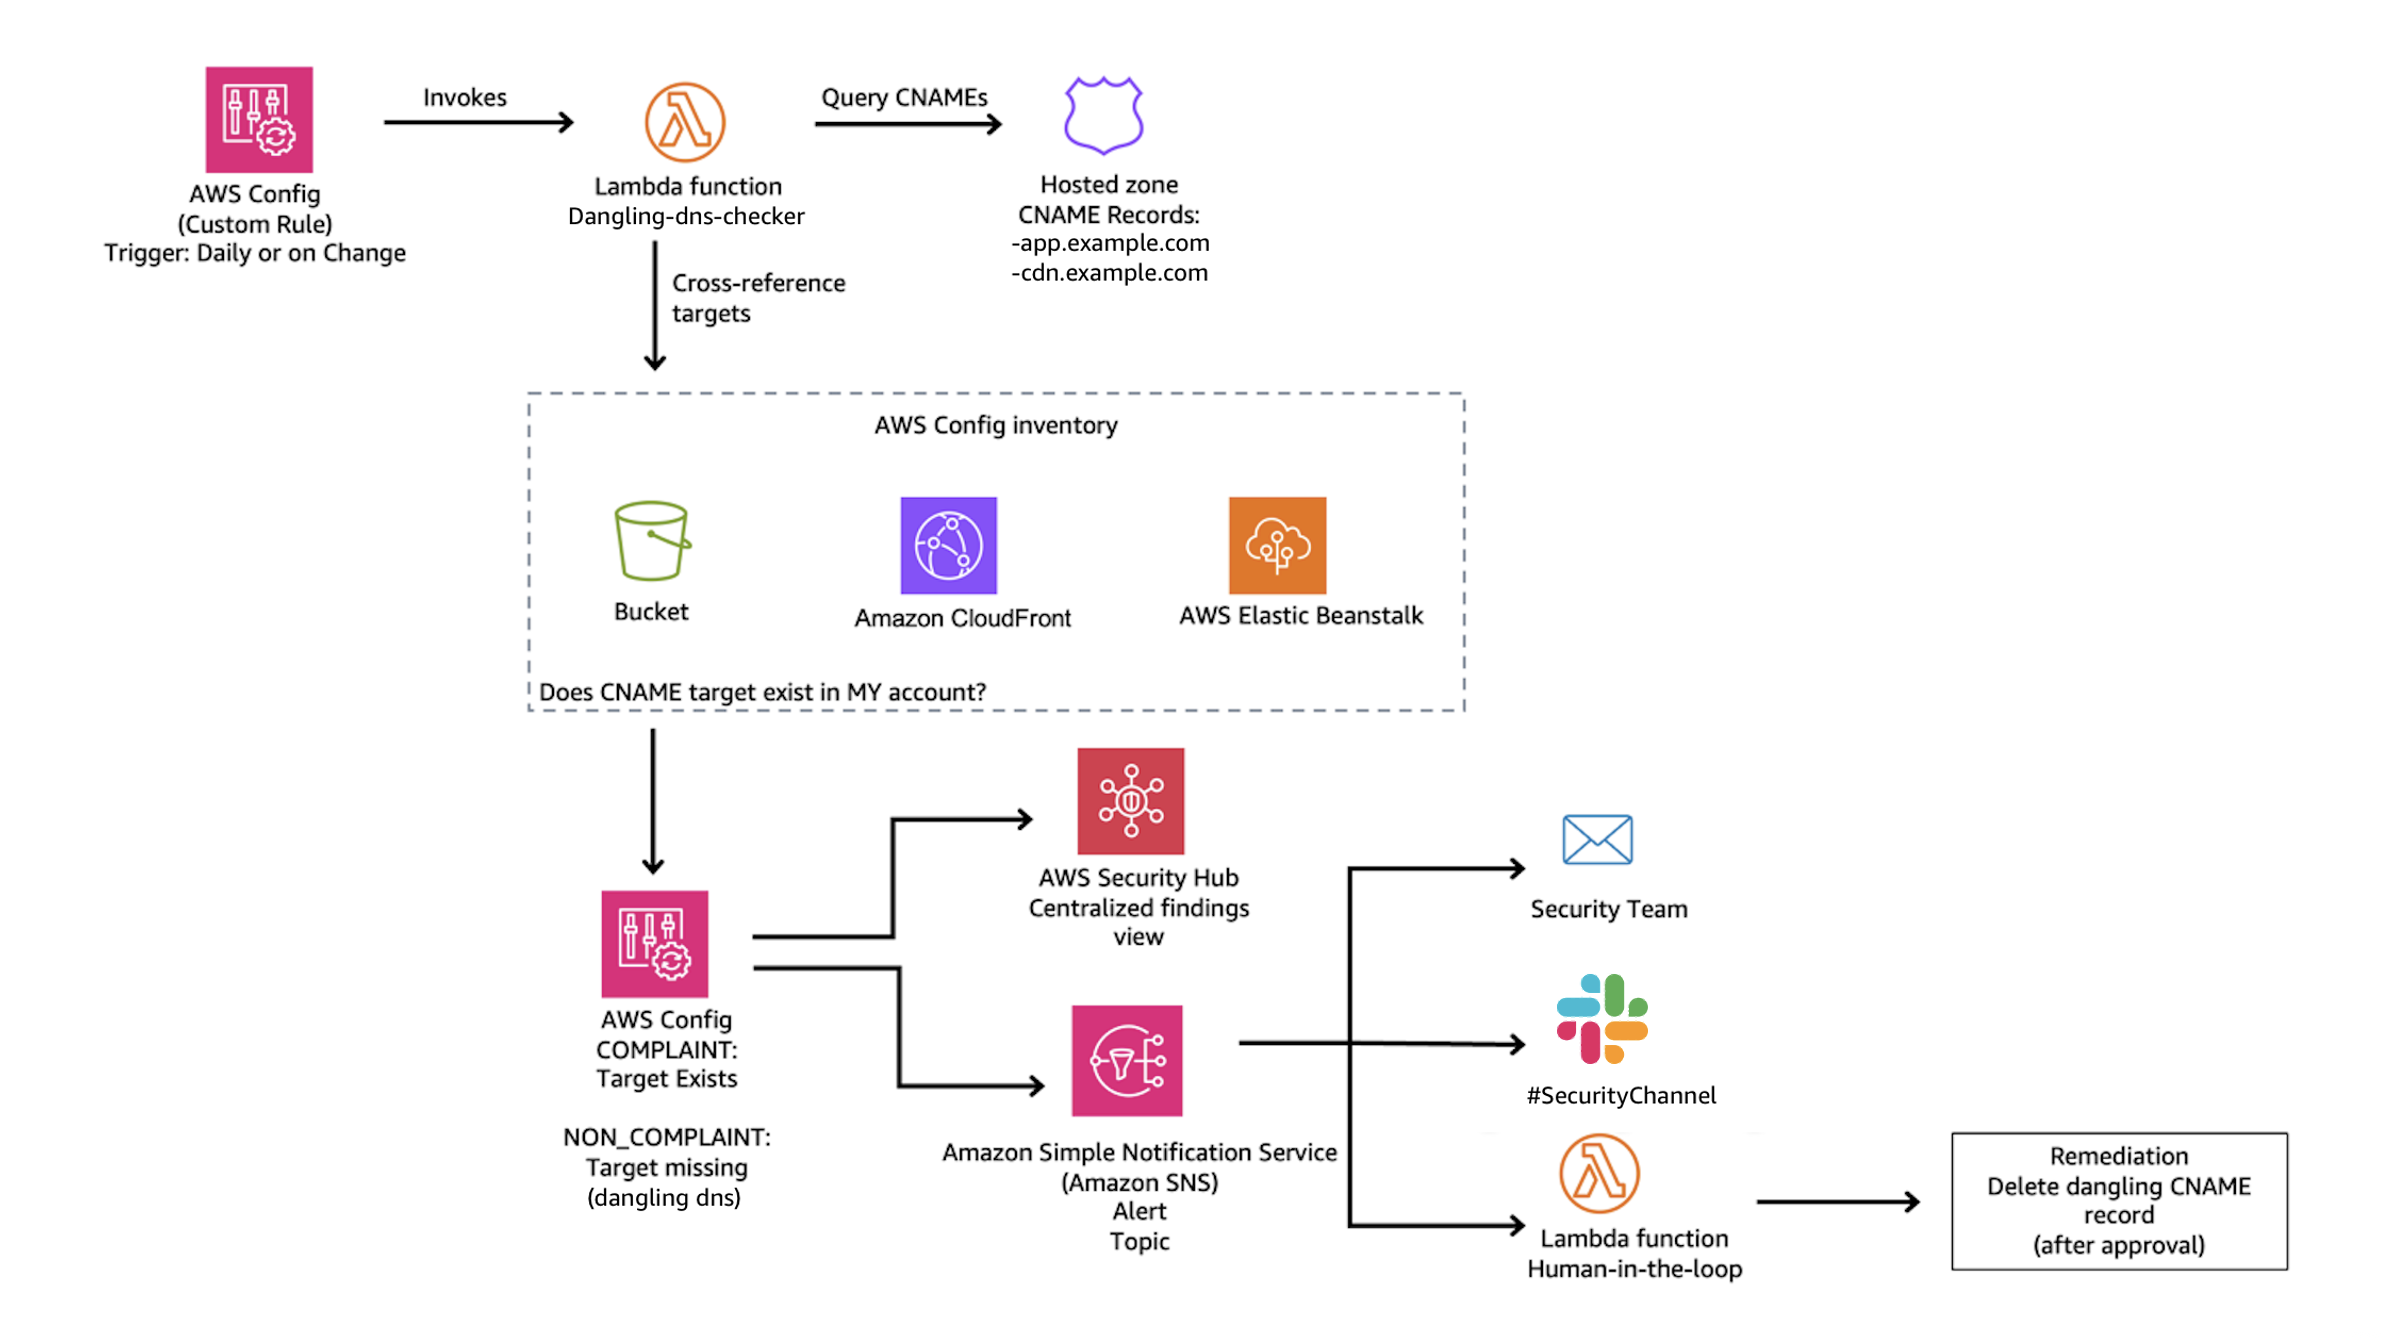
The main idea is to create a custom AWS Config rule that queries your Route 53 hosted zones for CNAME records, then parses each CNAME target to determine whether it points to a known AWS resource pattern such as S3, CloudFront, or Elastic Beanstalk. For each match, the rule cross-references the target against your AWS Config inventory to verify that the resource actually exists in your account. If the resource isn’t found, the rule marks the CNAME record as NON_COMPLIANT, surfacing it for review.

The Config rule should focus on known AWS resource patterns:

  • S3: *.s3.amazonaws.com, *.s3-website-<region>.amazonaws.com
  • CloudFront: *.cloudfront.net
  • Elastic Beanstalk: *.elasticbeanstalk.com

Note: CNAME records pointing to external third-party services are outside the scope of this detection mechanism, as those resources won’t appear in your AWS Config inventory.

NON_COMPLIANT findings from your Config rule can be routed to AWS Security Hub for centralized visibility, or trigger SNS notifications to alert your security team.

Figure 5: Dangling DNS Detection Solution

Figure 5: Dangling DNS Detection Solution

Reference implementation:

We’ve published a complete implementation of this detection approach as an open-source solution. The solution deploys a Lambda function that discovers CNAME records across all your Route 53 hosted zones and uses pattern matching to identify targets pointing to S3, CloudFront, and Elastic Beanstalk. It then queries your AWS Config inventory to verify whether each target resource still exists in your account. When a dangling record is detected, the solution generates a HIGH severity finding in Security Hub and can optionally send SNS notifications to alert your security team. A CloudWatch metrics dashboard is also included for ongoing compliance tracking.

Deployment:

# Clone the repository
git clone https://github.com/aws-samples/sample-dangling-dns-detection
cd sample-dangling-dns-detection

# Build the Lambda deployment package
./scripts/package.sh

# Upload to S3
aws s3 cp dist/dangling-dns-detection.zip s3://YOUR_BUCKET/

# Deploy the CloudFormation stack
aws cloudformation deploy \
  --template-file infrastructure/template.yaml \
  --stack-name dangling-dns-detection \
  --parameter-overrides \
      LambdaCodeS3Bucket=YOUR_BUCKET \
      EvaluationFrequency=TwentyFour_Hours \
  --capabilities CAPABILITY_NAMED_IAM

The stack creates an AWS Config custom rule that runs on your specified schedule (default: every 24 hours), evaluating all CNAME records and reporting compliance status.

Mitigating the effects

Mitigating subdomain takeover requires both preventive procedures and responsive capabilities.

Prevention: Standard operating procedure

The most effective mitigation is a standard operating procedure for resource deprovisioning that ensures DNS records are removed before the underlying resource:

  1. Within your DNS zone, delete the CNAME record that points to the fully qualified domain name (FQDN) of the resource that you plan to deprovision.
  2. Wait for the DNS TTL to expire before deleting the resource. DNS resolvers cache records for the duration of the TTL (for example, a TTL of 3600 means resolvers may serve the old record for up to one hour). If you delete the resource before the TTL expires, a threat actor could claim the resource name while cached CNAME entries are still directing traffic to it.
  3. Deprovision the resource that you no longer want to use.
  4. Run a DNS check of the CNAME record that you removed to verify that the resource is no longer resolving.

Key principle: Always delete DNS first, wait for the TTL to expire, then delete the resource. This order eliminates the window where a dangling record could be exploited.

Prevention: S3 account regional namespaces

As mentioned earlier, AWS introduced account regional namespaces for Amazon S3 general purpose buckets in March 2026. While this is a meaningful step toward mitigating the S3-specific takeover vector, there are important operational limitations to be aware of:

Existing buckets are unaffected. Buckets already created in the global namespace cannot be migrated to an account regional namespace. The bucket names remain globally unique and claimable by anyone if the bucket is deleted.

Global namespace is still the default. When creating a new bucket through the console, CLI, or SDK, the global namespace remains the default selection. Users who aren’t aware of the new option will continue creating globally-scoped buckets.

Existing IaC templates require updates. Existing infrastructure-as-code templates (CloudFormation, CDK, Terraform) that don’t explicitly opt in to the account regional namespace will continue provisioning buckets in the global namespace. For CloudFormation, this means setting the BucketNamespace property to account-regional. For other IaC tools, consult their documentation for the equivalent configuration. Organizations need to audit and update their templates to opt in.

For these reasons, the dangling DNS detection approach described in this post remains critical – particularly for organizations with existing S3 infrastructure, and for CloudFront, and Elastic Beanstalk resources where no equivalent namespace scoping exists.

Response: Notification and remediation

When a dangling DNS record is detected, the reference solution described in the Detection section automatically creates a HIGH severity finding in AWS Security Hub and reports the CNAME record as NON_COMPLIANT in AWS Config. If you provide an SNS topic ARN during deployment, the solution also sends notifications to alert your security or operations team via email, Slack, or other channels. For production environments, consider a human-in-the-loop workflow where these notifications are reviewed by a team member who approves the DNS record deletion before it’s executed. This prevents accidental deletion of legitimate records during transient issues.

The reference solution also includes a CloudWatch dashboard for tracking compliance status and evaluation metrics over time, giving your team ongoing visibility into DNS health across your hosted zones.

Note: Fully automated remediation (auto-deleting DNS records) carries risk – a false positive could disrupt legitimate services. We recommend starting with detection and notification, then evaluating automation based on your detection accuracy and operational maturity.

Conclusion

Subdomain takeover is a preventable misconfiguration that can have significant impact on your organization. A layered defense approach provides the best protection:

Prevention: Implement a standard operating procedure that deletes DNS records before deprovisioning the underlying resource.

Detection: Use AWS Config custom rules to proactively identify CNAME records pointing to resources that no longer exist in your account.

Response: Configure notifications through SNS or Security Hub so your team can respond quickly when dangling records are detected.

Monitoring: Maintain ongoing visibility through CloudWatch dashboards to track DNS health and compliance status.

The key insight is that good DNS hygiene – knowing when your CNAME records point to a nonexistent resource – is your first line of defense. Automated detection through AWS Config provides a safety net when operational procedures fail. And if you detect an issue, having a playbook ready to enact your response can lower the impact and your mean time to recovery.

If you have feedback about this post, submit comments in the Comments section below.


Matt Gurr

Matthew Gurr

Matthew is the Senior Incident Response lead in the Asia-Pacific region for the AWS Customer Incident Response Team (AWS CIRT). He has a passion for helping customers proactively prepare for a security event. In his spare time, he enjoys cycling, music, and reading.

Luis Pastor

Luis Pastor

Luis is a Senior Security Solutions Architect at AWS leading the Infrastructure Security and Compliance Technical Field Communities. He drives security architecture for enterprise customers across financial services, healthcare, and retail, specializing in cloud security transformation and regulatory compliance frameworks. Before AWS, Luis architected security solutions in hybrid cloud environments.

Geoff Sweet

Geoff Sweet

Geoff has been in industry since the late 1990s. He began his career in electrical engineering. Starting in IT during the dot-com boom, he has held a variety of diverse roles, such as systems architect, network architect, and, for the past several years, security architect. Geoff specializes in infrastructure security.

Ariam Michael

Ariam Michael

Ariam is a Solutions Architect at AWS. She has supported various customers in the Worldwide Public Sector, specifically SLG and Federal Civilian customers. She is passionate about security, specifically Data Protection helping customers implement encryption and best practices.

Regional routing for AWS access portals: Implementing custom vanity domains for IAM Identity Center

Post Syndicated from Georgi Baghdasaryan original https://aws.amazon.com/blogs/security/regional-routing-for-aws-access-portals-implementing-custom-vanity-domains-for-iam-identity-center/

AWS IAM Identity Center provides a web-based access portal that gives your workforce a single place to view their AWS accounts and applications. With the recent launch of IAM Identity Center multi-Region replication, customers can replicate their IAM Identity Center instance across multiple AWS Regions to improve resilience and reduce latency for a globally distributed workforce. As a result, users have a dedicated access portal URL in each Region where Identity Center is replicated, and where administrators need a consistent way to manage these portals to ensure that each user reaches the right one.

This post walks you through building a custom vanity domain (for example, aws.mycompany.com) that serves as a single, memorable entry point for access to IAM Identity Center through the AWS Management Console. The solution uses latency-based routing to automatically redirect users to their nearest healthy access portal endpoint and provides a mechanism to trigger failovers when a Regional Identity Center instance, or the broader AWS Region, is impaired. Because this solution operates outside of Identity Center—at the DNS and load balancer layer—users are transparently redirected to the appropriate Regional access portal URL. Note that the vanity domain itself will not appear in the browser’s address bar.

This guide is structured in three progressive phases: a single-Region redirect, multi-Region latency routing, and automatic health-based failover. You can adopt each phase independently, depending on your organization’s needs.

Note: While this guide focuses on IAM Identity Center access portal endpoints, the same approach using Amazon Route 53 latency-based routing, Application Load Balancer (ALB) redirects, and Amazon Application Recovery Controller (ARC) Region switch can be applied to build a custom vanity domain and intelligent routing layer for any other HTTP endpoint type.

Background

IAM Identity Center supports multiple access portal URL formats that resolve to the same web portal. The following table summarizes the supported formats in the standard AWS (classic) partition, along with their capabilities:

Format IPv4 Dual-stack Multi-Region* Example
https://{directoryId}.awsapps.com/start Yes No No https://d-1234567890.awsapps.com/start
https://{alias}.awsapps.com/start Yes No No https://mycompany.awsapps.com/start
https://{idcInstanceId}.{region}.portal.amazonaws.com Yes No Yes https://ssoins-1234567890.us-west-2.portal.amazonaws.com
https://{idcInstanceId}.portal.{region}.app.aws ★ Yes Yes Yes https://ssoins-1234567890.portal.us-west-2.app.aws

* Each Regional URL resolves only to its own Region’s portal instance and doesn’t fail over to another Region. Multi-Region here means the URL format is available in every Region where IAM Identity Center is replicated. To route users across Regions dynamically, use the vanity domain approach described in this post.

Note: The ★ highlighted row (https://{idcInstanceId}.portal.{region}.app.aws) is the recommended URL format. It supports both dual-stack (IPv4 and IPv6) and IAM Identity Center multi-Region replication. The awsapps.com formats aren’t always available in newer Regions and don’t support multi-Region capabilities. In additional replicated Regions, the custom alias isn’t supported, and the awsapps.com parent domain isn’t available.

Working with multiple Regional endpoints

As you expand your IAM Identity Center footprint through multi-Region replication, each replicated Region provides a dedicated access portal URL—directing your users to the low-latency entry point closest to their location. A user connecting from Europe and one connecting from Asia Pacific each benefit from their respective Regional endpoint. To deliver the best experience, organizations need a consistent, centrally managed way to direct users to the correct Regional destination; there are a few common approaches you can use to achieve this.

Customers typically start with a single Regional endpoint, which is straightforward to configure, but users in distant Regions experience higher latency, and a Regional incident can affect all users regardless of location. Others maintain per-Region bookmarks or configuration, which gives each user population the right endpoint but requires ongoing IT coordination and clear communication to users.

Custom vanity domains give you full control over DNS routing, health checks, and failover of your access portal connections; all behind a single, brand-aligned domain name (for example, aws.mycompany.com) that users access. A vanity domain makes this start URL memorable and consistent for users, regardless of the underlying IAM Identity Center configuration – a single address to remember and share, compared to maintaining a separate bookmark for each Regional endpoint or managing a growing list of application tiles in your external identity provider. The rest of this guide walks you through how to deploy this solution step by step.

Solution overview

The solution builds a lightweight routing and redirect layer in front of the IAM Identity Center access portal Regional endpoints. The architecture has the following components:

  • AWS IAM Identity Center – Your existing Identity Center instance
  • Amazon Route 53 – Manages your vanity domain’s hosted zone, latency-based routing policy, and health checks
  • AWS Certificate Manager (ACM) – Issues and automatically renews TLS certificates for your vanity domain in each Region
  • Application Load Balancer (ALB) – Handles HTTP and HTTPS traffic, issuing 302 redirects to the appropriate Regional access portal endpoint
  • Amazon Application Recovery Controller (ARC) Region switch – Orchestrates Regional failovers by controlling Route 53 health check states, so traffic is automatically shifted away from an unhealthy Region

This guide is structured in three progressive phases. You can adopt each phase incrementally based on your needs:

  • Phase 1: Sets up the vanity domain with a redirect to a single Regional access portal endpoint. Suitable for organizations with a single-Region Identity Center deployment.
  • Phase 2: Extends Phase 1 across multiple Regions with latency-based routing, so users are automatically directed to the nearest Regional endpoint. Requires IAM Identity Center multi-Region replication.
  • Phase 3: Adds an ARC Region switch for managed Regional failover. Without Phase 3, a Regional impairment requires manual DNS updates to redirect traffic. ARC automates this with rehearsable, controlled failover plans.

Figure 1: Solution architecture for custom vanity domain routing with IAM Identity Center.

When a user navigates to aws.mycompany.com, the following happens:

  1. Route 53 evaluates the latency records and routes traffic to the ALB in the lowest-latency healthy Region.
  2. The ALB terminates TLS using an ACM-managed certificate and issues a 302 redirect to the corresponding Regional Identity Center access portal URL.
  3. The user’s browser follows the redirect and loads the access portal directly. Subsequent authentication traffic flows between the browser and AWS—the ALB isn’t in the path.

If you’ve implemented Phase 3, ARC controls Route 53 health check states for each Region. With this configuration, you can stop routing traffic to any Region considered unhealthy.

Prerequisites

Before you begin to build the solution, ensure you have the following in place:

  1. An existing top-level domain (TLD) (for example, mycompany.com).
  2. An AWS IAM Identity Center organization instance configured.
  3. For Phases 2 and 3, you need IAM Identity Center multi-Region replication configured with at least two Regions. See Setting up IAM Identity Center multi-Region replication for instructions.
  4. AWS Identity and Access Management (IAM) permissions on a dedicated networking or shared services account in your organization to manage Route 53, ACM, Amazon Elastic Compute Cloud (Amazon EC2), ALB (phase 1 and 2), and ARC (phase 3).

Phase 1: Redirect to a single predefined access portal endpoint

In this phase, you create the foundational infrastructure: a Route 53 hosted zone, an ACM-managed TLS certificate, and an internet-facing ALB that issues a 302 redirect to your Regional access portal URL. By the end, users who navigate to aws.mycompany.com will be seamlessly redirected to your Identity Center portal.

Create a Route 53 hosted zone for your vanity domain

The hosted zone holds the DNS records that control how aws.mycompany.com resolves. If your top-level domain (mycompany.com) is already registered in Route 53, you create a subdomain hosted zone. If it’s registered with another registrar, you create a public hosted zone and configure name server (NS) delegation manually.

  1. In the AWS Management Console, navigate to Route 53 and choose Hosted zones, then Create hosted zone.
  2. Enter your vanity domain in the Domain name field (for example, aws.mycompany.com).
  3. Select Public hosted zone as the type, then choose Create hosted zone.
  4. Note the four NS records that Route 53 creates for the new hosted zone. You will need these in the next step.

Figure 2: Route 53 hosted zone details

Delegate your subdomain from the parent domain

To make Route 53 authoritative for aws.mycompany.com, you must add an NS record in the parent zone (mycompany.com) pointing to the name servers of the new hosted zone.

  • If mycompany.com is hosted in Route 53: Open the mycompany.com hosted zone, choose Create record, set the record name to aws, the type to NS, and paste the four NS values from the previous step. Choose Create records.
  • If mycompany.com is hosted elsewhere: Sign in to your registrar’s DNS management console and add an NS record for aws.mycompany.com using the four name server values from the previous step.

Note: DNS propagation for NS delegation can take up to 48 hours, though it typically completes within a few minutes for Route 53-to-Route 53 delegation.

Figure 3: Create a NS record type to delegate your subdomain from the parent domain

Request an ACM certificate

Your ALB requires a TLS certificate for aws.mycompany.com to serve HTTPS traffic. ACM provides free public certificates with automatic renewal.

  1. Go to the Certificate Manager console in the primary Region of IAM Identity Center (for example, us-east-2) and choose Request a certificate.
  2. Select Request a public certificate and choose Next.
  3. Enter your domain name (for example, aws.mycompany.com). Choose Add another name to this certificate and enter your Regional sub-domain (for example, us-east-2.aws.mycompany.com).
  4. Leave other options as defaults (Disable export, DNS validation – recommended, and key algorithm – RSA 2048) and choose Request.
  5. In the certificate details page, choose Create records in Route 53. ACM will automatically add the validation CNAME records to your hosted zone. The certificate status changes to Issued within a few minutes.

Figure 4: Request an ACM certificate for your domain

Create a security group for Identity Center ALB

The security group needs to allow inbound HTTP and HTTPS traffic for both IPv4 and IPv6 from the public internet to make the load balancer reachable.

  1. Go to the Amazon EC2 console, navigate to Security Groups, and choose Create security group.
  2. Enter a Name (for example, identitycenter-global-domain-alb-sg-us-east-2) and Description. Add four rules by choosing Add Rule under Inbound Rules.
    1. Set Type to HTTP, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
    2. Set Type to HTTPS, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
  3. Choose Add Rule under Outbound Rules and set Type to All traffic and Source to Anywhere-IPv6 (::/0).
  4. Choose Create security group.

Figure 5: ALB security group rules

Create an ALB with an HTTP and HTTPS redirect rule

The ALB is the component that performs the actual redirect to your IAM Identity Center access portal URL. The ALB listener accepts HTTPS requests on port 443 and responds with a 302 redirect to the appropriate Regional Identity Center access portal endpoint.

  1. Go to the Amazon EC2 console, navigate to Load Balancers, and choose Create load balancer. Select Application Load Balancer.
  2. Enter a name for your ALB (for example, identitycenter-redirect-alb).
  3. Configure basic settings: Set the scheme to Internet-facing, IP address type to Dualstack (or IPv4 if IPv6 isn’t supported by your virtual private cloud (VPC)), and select at least two Availability Zones. Ensure that the load balancer is operating in a VPC and subnets that are internet-facing.
  4. Under Security Groups choose the Security Group created in the previous step.
  5. Configure an HTTP listener: Add a listener on port 80 (HTTP) with Redirect to URL option. Choose URL parts and set Protocol to HTTPS, Port to 443, and status code to 302 (Found).

    Figure 6: Add an HTTP listener during ALB creation

  6. Configure an HTTPS listener: Add a listener on port 443 (HTTPS) with No pre-routing action (default) and Redirect to URL options. Choose Full URL and set the URL to your Regional Identity Center access portal endpoint (For example, https://ssoins-1234567890.portal.<your-region>.app.aws, for this blog the region is us-east-1). Set status code to 302 (Found).

    Figure 7: Add an HTTPS listener

  7. Under Default SSL/TLS certificate, select the ACM certificate you created in Step 3.

    Note: Make sure to select 302 – Found as the Status code. Selecting 301 – Permanently moved will result in browser caching the redirect URL which will prevent failovers from working correctly until the cache expires.

Create Regional Route 53 records pointing to your ALB

Create a DNS record in your hosted zone that resolves <your-region>.aws.mycompany.com to your ALB.

  1. Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
  2. Set the record name to the AWS Region name (For example: us-east-2) and the record type to A.
  3. Toggle Alias and in the drop down menu Route traffic to, select the alias target to Alias to Application and Classic Load Balancer, select your Region (For example:us-east-2), and select your ALB from the dropdown list.
  4. Leave routing policy as Simple routing, and select the Region (For example:us-east-2) and choose Create records.
  5. Repeat steps 1 through 4 to create AAAA record types.

Figure 8: Route 53 record with simple routing policy

Add latency-based routing configurations

Finally, create a DNS record in your hosted zone that resolves aws.mycompany.com to your Regional Route 53 record.

  1. Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
  2. Keep the subdomain name for this record as empty, so aws.mycompany.com is the fully qualified record and set the record type to A.
  3. Enable alias: Set the Route traffic to Alias to another record in this hosted zone, and select the hosted zone you created earlier (us-east-2.aws.mycompany.com).
  4. Set Routing Policy to Latency and select the corresponding Region (us-east-2 in this example).
  5. Add a clear name for the Record ID, such as us-east-2--ipv4 as a differentiator and choose Create records.
  6. Repeat the steps 1 through 5 to create AAAA record types with us-east-2--ipv6 as the record ID.
Figure 9: Route 53 record with latency-based routing

Figure 9: Route 53 record with latency-based routing

Test the configuration by navigating to https://aws.mycompany.com in a browser. You should be redirected to your Identity Center access portal. You can also validate using:
curl -I https://aws.mycompany.com

Expected response:

HTTP/2 302

location: https://ssoins-1234567890.portal.<your-region>.app.aws

Tip: To deploy Phase 1 automatically, download the CloudFormation template from the Deploying with CloudFormation section below.

Phase 2: Automatically route to the nearest Regional access portal endpoint

Phase 2 extends the solution to support IAM Identity Center multi-Region replication by deploying an ALB in each replicated Region and configuring Route 53 latency-based routing. Users are automatically directed to the access portal in the Region that has the lowest network latency from their location, which matches the active-active behavior of the Identity Center access portal itself.

Request ACM certificates in each additional Region

Repeat the steps from Request an ACM Certificate for each additional Region (for example, us-west-2) where you’ve replicated IAM Identity Center.

Create a security group and an ALB in each additional Region

Repeat the steps from Create a security group for Identity Center ALB and Create an ALB with an HTTP and HTTPS redirect rule in each additional Region. In each ALB’s redirect rule, set the target URL to the access portal endpoint for that specific Region. For example:

  • us-east-2 ALB redirects to https://ssoins-1234567890.portal.us-east-2.app.aws
  • us-west-2 ALB redirects to https://ssoins-1234567890.portal.us.west-2.app.aws

Create Regional and latency Route 53 records for the additional Region

For each additional Region where you’ve deployed an ALB and replicated Identity Center, create Regional and latency A and AAAA records as outlined in Create Regional Route 53 records pointing to your ALB and Add latency-based routing configurations.

Tip: To deploy Phase 2 automatically, download the CloudFormation template from the following Deploying with CloudFormation section.

Phase 3: Regional failover using ARC Region switch

Phase 3 introduces Amazon Application Recovery Controller (ARC) Region switch, a fully managed capability that you can use to plan, practice, and orchestrate Regional failovers with confidence. ARC Region switch vends Route 53 health checks directly as part of a Region switch plan. You attach these generated health checks to your Route 53 latency records, and ARC controls their healthy or unhealthy state during plan execution. You can further extend the solution to include custom automation triggered by Amazon CloudWatch alarms or synthetic canaries to update routing control state.

We recommend creating your ARC Region switch plan in the primary Region of your IAM Identity Center for ease of discovery.

Create an active-active instance of ARC Region switch plan

Create an ARC Region switch plan that will orchestrate failovers between your IAM Identity Center Regions and auto-generate the Route 53 health checks you will reference in the next step.

  1. Open the Application Recovery Controller console and choose Region switch in the navigation pane. Select Create Region Switch Plan.
  2. Enter a Plan name (for example, idc-access-portal-failover) and an optional description. Choose Active/Active for Multi-Region recovery approach. Select the Regions where IAM Identity Center is replicated ,including the primary Region.
  3. In the Execution Permission section, enter the Amazon Resource Name (ARN) of the IAM role that ARC will use to update Route 53 health check states during plan execution. If you don’t have an existing role, choose Create a new role to have ARC create one automatically. See AWS Managed Policy: AmazonApplicationRecoveryControllerRegionSwitchPlanExecutionPolicy for information about required permissions.
  4. Choose Create Plan and proceed to Build workflows. Enter optional descriptions and choose Save and continue.

    Figure 10: Region switch plan

  5. Set the Workflow type to Activate and set the Region to the corresponding Region (us-east-2 or us-west-2). Within each workflow, choose Add step/Run in Sequence. Choose an execution block to Amazon Route 53 health check execution blog under Networking.
  6. Choose Add and edit. Enter a Step name (for example, Activate Route53 Record Set).
  7. Set the Hosted zone to the hosted zone ID for your aws.mycompany.com domain, and set the Record name to aws.mycompany.com.
  8. Expand Record set identifiers. Choose Add record set identifier and enter a unique identifier for the record set (for example, us-east-2--ipv4 and us-east2--ipv6) and select your Region. Add two record set identifiers (A and AAAA records) for each of your Regions.
  9. Choose Save step.
  10. Repeat steps 5 and 6 for Deactivate and choose Save the plan.

    Figure 11: Workflow builder

  11. Choose Save workflows.
  12. Select the newly created plan and choose the Monitoring tab. Note the IDs of the health checks created.

    Figure 12: IAM Identity Center access portal plan

Update Route 53 record sets to reference ARC-managed health checks

Associate the ARC-generated health check IDs with the latency-based A and AAAA records you created in Phase 1 and 2. Route 53 uses these health checks—which are now controlled by ARC—to determine which Regions are eligible for DNS resolution. Route 53 still uses latency to choose from the healthy Regions.

    1. Go to the Route 53 console and choose Hosted zones.
    2. Select the hosted zone for aws.mycompany.com.
    3. Find the latency-based A record for us-east-2 that you created in Phase 2, and choose Edit record.
    4. In the Health check section, enable Associate with a health check. In the Health check ID dropdown, select the ARC-generated health check for us-east-2 that you noted at the end of the preceding procedure. Note: Ignore the warning This health check ID doesn’t belong to this AWS account. Make sure you have copied it accurately to use it.
    5. Choose Save changes.
    6. Repeat steps 3, 4, and 5 for A and AAAA records for each of your IAM Identity Center Regions.

Figure 13: Update Route53 record sets

Validate the setup by performing a failover

Validate the end-to-end configuration by executing a controlled failover. Because latency-based routing will always resolve aws.mycompany.com to us-east-2 for users in the primary geography, deactivating us-east-2 is the most direct way to confirm that Route 53 correctly fails over to us-west-2.

    1. Before executing the failover, confirm that aws.mycompany.com is resolving to the us-east-2:
      curl -I https://aws.mycompany.com
      Expected: A record pointing to the us-east-2 access portal URL (for example, https://ssoins-1234567890.portal.us-east-2.app.aws:443/).
    2. Go to the Amazon Application Recovery Controller console. In the left navigation pane, choose Region switch.
    3. Select your Region switch plan (idc-access-portal-failover) to open the plan details page.
    4. Choose Execute recovery.
    5. On the Execute plan page, select us-east-2 as the Region to fail out of.
    6. Select the Deactivate action and choose Start execution. ARC sets the us-east-2 health check to unhealthy. Route 53 stops resolving aws.mycompany.com to the us-east-2 ALB and routes traffic to us-west-2 instead.
    7. After a few seconds, confirm the failover has taken effect:
      curl -I https://aws.mycompany.com
      Expected: 302 redirect to the us-west-2 IAM Identity Center access portal URL
    8. To fail back, choose Execute plan again. Select us-east-2, select the Activate action and choose Start execution. ARC marks the us-east-2 health check healthy and Route 53 resumes routing traffic to that Region.

Tip: To deploy Phase 3 automatically, download the CloudFormation template from the Deploying with CloudFormation section that follows.

Deploying with CloudFormation

As an alternative to the manual console steps described previously, we provide CloudFormation templates that you can download and deploy for each phase. Each template is self-contained and parameterized, so you only need to provide your environment-specific values (such as your vanity domain name, VPC, and subnet IDs). Download the templates from the following links:

To deploy a template, navigate to the AWS CloudFormation console, choose Create stack, select Upload a template file, and upload the downloaded YAML file. Follow the prompts to provide parameter values and create the stack. For Phase 2, deploy the template once in each additional Region.

Deploy all phases with a single scrip

As an alternative to deploying each CloudFormation template individually, you can use the provided deploy.sh bash script to deploy all three phases in sequence. The script automates stack creation across your primary and additional Region. To get started, download the deployment package, then unzip the file into a local directory:

wget https://aws-security-blog-content.s3.us-east-1.amazonaws.com/public/sample/3536-regional-routing-for-aws-access-portals/Vanity-domains-cfn.zip
unzip  Vanity-domains-cfn.zip
cd Vanity-domains-cfn

Before running the script, open the deploy.sh file and update the following required parameters with your environment-specific values:

  • TLD – Your top-level domain (for example, mycompany.com)
  • TLD_HOSTED_ZONE_ID – The Route 53 hosted zone ID for your top-level domain
  • IDC_SUBDOMAIN – The Identity Center subdomain name (for example, aws)
  • IDC_INSTANCE_ID – Your IAM Identity Center instance ID (for example, ssoins-1234567890)
  • PRIMARY_REGION – The primary Region for your Identity Center instance (for example, us-east-2)
  • ADDITIONAL_REGIONS – The additional Region for multi-Region replication (for example, us-west-2)

After updating the configuration, run the deployment script:

./deploy.sh

The script deploys Phase 1 (single-Region redirect), Phase 2 (multi-Region latency-based routing), and Phase 3 (ARC Region switch failover) in order. Monitor the terminal output for stack creation progress and any errors.

After completing the setup, you can integrate the vanity URL (for example, aws.mycompany.com) directly into your identity provider, such as Okta or Microsoft Entra ID, as a bookmark application or a chiclet URL. By configuring the vanity URL as the bookmark target, users who launch the application from their identity provider dashboard are always redirected to the nearest IAM Identity Center access portal endpoint through latency-based routing. If a Regional impairment occurs and a failover is necessary, administrators can execute an ARC Region switch to deactivate the impaired Region, and users will automatically be redirected to the active Identity Center endpoint without any change to the bookmark URL or end-user experience.

Conclusion

In this post, you learned how to build a custom vanity domain for an AWS IAM Identity Center access portal using Amazon Route 53, AWS Certificate Manager, Application Load Balancer, and an Amazon Application Recovery Controller (ARC) Region switch. The three-phase approach lets you start with a single-Region redirect, progressively add latency-based routing as your IAM Identity Center footprint grows with multi-Region replication, and then introduce an ARC Region switch to gain fully managed, rehearsable Regional failover.

For more information about IAM Identity Center multi-Region replication, see the IAM Identity Center User Guide. For more resilience patterns, visit the AWS Architecture Blog posts about Resilience. If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Resources


Georgi Baghdasaryan

Georgi Baghdasaryan

Georgi is a Principal Engineer at Amazon Web Services, where he builds identity systems that help organizations securely manage access and authentication at scale. His broader focus is on reliable, high-impact infrastructure that enables customers to operate confidently in the cloud. Outside of work, Georgi enjoys experimenting with new matcha latte recipes and going on long bike rides.

Sowjanya Rajavaram

Sowjanya Rajavaram

Sowjanya is a Sr Solutions Architect who specializes in Identity and Security in AWS. She works on helping customers of all sizes solve their identity and access management problems. She enjoys traveling and exploring new cultures and food.

Author

Laura Reith

Laura is an Identity Solutions Architect at AWS, where she thrives on helping customers overcome security and identity challenges. In her free time, she enjoys wreck diving and traveling around the world.

Secure multi-warehouse Amazon Redshift access behind a Network Load Balancer using Microsoft Entra ID

Post Syndicated from Raghu Kuppala original https://aws.amazon.com/blogs/big-data/secure-multi-warehouse-amazon-redshift-access-behind-a-network-load-balancer-using-microsoft-entra-id/

As data analytics workloads scale, organizations face two challenges. First, they must deliver high-performance analytics at massive scale while maintaining secure access across diverse tools. Second, they must manage high-concurrency workloads while integrating with existing identity management systems.

You can address these challenges by using Amazon Redshift Serverless endpoints behind an AWS Network Load Balancer with Microsoft Entra ID federation. This architecture can authenticate while helping to streamline identity management across your data environment. Amazon Redshift Serverless provides petabyte-scale analytics with auto scaling capabilities, enabling high-concurrency workloads while streamlining user authentication and authorization.

In this post, we show you how to configure a native identity provider (IdP) federation for Amazon Redshift Serverless using Network Load Balancer. You will learn how to enable secure connections from tools like DBeaver and Power BI while maintaining your enterprise security standards.

Solution overview

The following diagram shows the architecture.

Figure 1: Sample architecture diagram

Figure 1: Sample architecture diagram

In this architecture:

  • A central Amazon Redshift ETL data warehouse shares data to multiple Amazon Redshift Serverless workgroups using Amazon Redshift data sharing.
  • Each workgroup has a dedicated managed Amazon Virtual Private Cloud (Amazon VPC) endpoint.
  • A Network Load Balancer sits in front of all VPC endpoints, providing a single connection point.
  • Users connect from DBeaver or Power BI through the Network Load Balancer and authenticate using their Microsoft Entra ID credentials.

This setup works whether you’re validating the concept with a single workgroup today or planning to scale to multiple workgroups in the future.

Prerequisites

Before you begin, make sure that you have completed these prerequisites.

  1. Create Amazon Redshift Serverless endpoints.
  2. Set up datashare from producer to Amazon Redshift Serverless endpoints.
  3. Create Amazon Redshift-managed VPC endpoints.
  4. Create a Network Load Balancer.
  5. Configure a domain name.
  6. Set up Amazon Redshift native IdP federation with Microsoft Entra ID.
  7. Gather the following from your registered application in Microsoft Entra ID:
    1. Scope (API-Scope)
    2. Azure Client ID (AppID from App Registration Details)
    3. IdP Tenant (Tenant ID from App Registration Details)
  8. Download and install the latest Amazon Redshift JDBC and ODBC drivers.

This solution uses the following AWS services.

Implementation steps

This section covers configuring the Network Load Balancer, setting up an ACM certificate, creating custom domain names in Amazon Redshift, configuring DNS records in Amazon Route 53, and connecting your JDBC and ODBC clients using Microsoft Entra ID authentication.

1. Configure the Network Load Balancer

First, collect the private IP addresses for your Amazon Redshift-managed VPC endpoints:

  1. Open the Amazon Redshift Serverless console.
  2. Choose your workgroup.
  3. Note the private IP address of your Redshift-managed VPC endpoint.
  4. Repeat for each Amazon Redshift Serverless endpoint that you want to add to the Network Load Balancer.

    Figure 2: Amazon Redshift managed VPC endpoint

    Figure 2: Amazon Redshift managed VPC endpoint

Next, create a target group for your endpoints:

  1. Open the Amazon Elastic Compute Cloud (Amazon EC2) console.
  2. Choose Target Groups.
  3. Choose Create target group.
  4. Configure the target group:
    • For Target type, choose IP addresses.
    • For Target group name, enter rs-multicluster-tg.
    • For Protocol, choose TCP.
    • For Port, enter 5439 (Note: You can find your specific port number in the Redshift endpoint connection details. If you haven’t modified it, use the default port 5439.).
    • For VPC, select your VPC.
    • Choose Next.
    Figure 3: create target group in NLB

    Figure 3: create target group in NLB

    Figure 4: NLB target group creation

    Figure 4: NLB target group creation

Add a listener to your Network Load Balancer:

  1. In the EC2 console, choose Load Balancers.
  2. Select your Network Load Balancer.
  3. In the Listeners tab, choose Add listener.
  4. Configure the listener:
    • For Protocol, choose TCP.
    • For Port, enter 5439.
    • For Default action, choose rs-multicluster-tg.
  5. Choose Add listener.

    Figure 5: NLB listener properties.

    Figure 5: NLB listener properties.

2. Configure AWS Certificate Manager (ACM)

For this example, we use myexampledomain.com as a custom domain. Replace it with your own domain name before you begin.Follow these steps to request and configure your certificate:

  1. Request a certificate in AWS Certificate Manager (ACM):
    • Open the AWS Certificate Manager console.
    • Choose Request Certificate.
    • Choose Request Public certificate.
    • Choose Next.
  2. Configure the certificate:
    • Add two domain names:
      • Network Load Balancer CNAME: dev-redshift.myexampledomain.com
      • Wildcard domain: *.redshift.myexampledomain.com
    • For Validation method, choose DNS validation.
    • Choose Request.

    For enhanced security, we recommend adding individual Amazon Redshift Serverless CNAMEs instead of using wildcards (*). This example uses DNS validation in AWS Certificate Manager, which requires creating CNAME records to prove domain control.

    Figure 6: AWS Certificate Manager (ACM) certificate creation

    Figure 6: AWS Certificate Manager (ACM) certificate creation

  3. Validate the certificate:
    • Your AWS Certificate Manager (ACM) certificate initially shows a ‘Pending validation’ status.
    • Wait for the status to change to ‘Issued’ before proceeding.
    • You must have an ‘Issued’ status before creating Amazon Redshift custom domain names.
    Figure 7: Sample issued AWS Certificate Manager (ACM) certificate

    Figure 7: Sample issued AWS Certificate Manager (ACM) certificate

3. Configure Amazon Redshift custom domain names

  1. Create a custom domain name:
    • Open the Amazon Redshift Serverless console.
    • Select your workgroup.
    • From Actions, choose Create custom domain name.
    Figure 8: Amazon Redshift custom domain name creation

    Figure 8: Amazon Redshift custom domain name creation

  2. Configure the domain settings:
    • For Custom domain name, enter cluster-02.redshift.myexampledomain.com.
    • For ACM certificate, select the certificate you created for dev-redshift.myexampledomain.com.
    • Choose Create.
    Figure 9: Amazon Redshift custom domain name creation

    Figure 9: Amazon Redshift custom domain name creation

  3. Verify that the custom domain name appears in your workgroup.

    Figure 10: Amazon Redshift custom domain name

    Figure 10: Amazon Redshift custom domain name

  4. Repeat steps 1–3 for each remaining Amazon Redshift Serverless endpoint that you want to add to the Network Load Balancer. Use a unique custom domain name for each endpoint (for example, cluster-03.redshift.myexampledomain.com, cluster-04.redshift.myexampledomain.com) and select the same ACM certificate that you created earlier.

4. Configure Amazon Route 53

Amazon Route 53 maps your custom domain name to the correct Amazon Redshift endpoint, making it reachable by name rather than a system-generated address. Without it, clients have no way to resolve your custom domain and AWS Certificate Manager can’t verify domain ownership to enable secure connections.First, create a CNAME record for your Network Load Balancer:

  1. Get the Network Load Balancer DNS name:
    • Open the Amazon EC2 console.
    • Choose Load Balancers.
    • Select your Network Load Balancer.
    • Copy the DNS name.
    Figure 11: NLB DNS name

    Figure 11: NLB DNS name

  2. Create Route 53 records:
    • Open the Amazon Route 53 console.
    • Choose Hosted Zones.
    • Select myexampledomain.com.
    • Choose Create record.
    • Configure the record:
      • For Record name, enter dev-redshift.myexampledomain.com.
      • For Record type, choose A – Routes traffic to an IPv4 address and some AWS resources.
      • For Alias, choose Yes.
      • For Route traffic to, choose Alias to Network Load Balancer.
      • Select your AWS Region and Network Load Balancer DNS name.
      • For Routing policy, choose Simple routing.
      • Choose Create records.
    Figure 12: NLB - A record in route 53

    Figure 12: NLB – A record in route 53

    Figure 13: NLB - A record in Route 53

    Figure 13: NLB – A record in Route 53

  3. Create the AWS Certificate Manager (ACM) validation CNAME:
    • Open AWS Certificate Manager.
    • Select your certificate for dev-redshift.myexampledomain.com.
    • Copy the CNAME name and CNAME value.
    • Return to Route 53.
    • Create a CNAME record in your myexampledomain.com hosted zone using the values from AWS Certificate Manager (ACM).
    • Choose Create records.
    Figure 14: NLB – CNAME record in Route 53

    Figure 14: NLB – CNAME record in Route 53

5. Configure Amazon Redshift JDBC and ODBC drivers with native IdP

The JDBC and ODBC driver configuration connects your client applications to Amazon Redshift through the Network Load Balancer using your Microsoft Entra ID credentials for authentication. Configuring both drivers allows any tool, whether DBeaver using JDBC or Power BI using ODBC, to authenticate through the same identity provider and reach the correct Amazon Redshift endpoint through a single connection point.

JDBC driver setup in DBeaver

  1. Create a new Amazon Redshift connection:
    • Host: dev-redshift.myexampledomain.com (NLB CNAME).
    • Database: dev.
    • Authentication: Database Native.
    • Username: login id for a user account.
    Figure 15: Amazon Redshift JDBC driver setup

    Figure 15: Amazon Redshift JDBC driver setup

  2. Configure driver properties:
    • plugin_name: com.amazon.redshift.plugin.BrowserAzureOAuth2CredentialsProvider.
    • sslmode: verify-ca.
  3. Add user driver properties:
    • client_id: [Your Microsoft Entra ID application client ID].
    • idp_tenant: [Your Microsoft Entra ID tenant].
    • listen_port: 7890.
    • loginTimeout: 60.
    • scope: [Your Microsoft Entra ID application scope].
    Figure 16: Amazon Redshift JDBC driver user properties

    Figure 16: Amazon Redshift JDBC driver user properties

ODBC driver setup

  1. Configure the system DSN:
    • Open ODBC Data Source Administrator (64-bit).
    • Choose System DSN.
    • Choose Add.
    • Select Amazon Redshift ODBC Driver (x64) 2.01.04.00.
    • Choose Finish.
  2. Configure connection settings:
    • Data Source Name: dev-redshift.
    • Server: dev-redshift.myexampledomain.com.
    • Port: 5439.
    • Database: dev.
    • Auth type: Identity Provider: Browser Azure AD OAUTH2.
    • Scope: [Your Microsoft Entra ID application scope].
    • Azure Client ID: [Your Microsoft Entra ID application client ID].
    • IdP Tenant: [Your Microsoft Entra ID application tenant].
    Figure 17: Amazon Redshift ODBC driver properties

    Figure 17: Amazon Redshift ODBC driver properties

  3. Configure SSL settings:
    • SSL Mode: verify-ca.
    • Choose Save.
    Figure 18: Amazon Redshift ODBC driver properties

    Figure 18: Amazon Redshift ODBC driver properties

6. Validate connectivity

Test DBeaver connection

  1. After configuring the JDBC driver properties, choose Test Connection.
  2. Authenticate through the Microsoft login in your browser.
  3. Verify that you receive a success message.
  4. Confirm successful connection using Native IdP through the Network Load Balancer.
Figure 19: Microsoft Entra id authentication

Figure 19: Microsoft Entra id authentication

Figure 20: Successful Microsoft Entra id authentication

Figure 20: Successful Microsoft Entra id authentication

Figure 21: Successful Amazon Redshift authentication

Figure 21: Successful Amazon Redshift authentication

Test power BI desktop connection

  1. Launch Power BI Desktop:
    • Choose Get data.
    • Choose More.
    • Under Other, select ODBC.
    • Choose Connect.
    Figure 22: Power BI desktop connectivity using Amazon Redshift ODBC driver

    Figure 22: Power BI desktop connectivity using Amazon Redshift ODBC driver

    Figure 23: Power BI desktop connectivity using Amazon Redshift ODBC driver

    Figure 23: Power BI desktop connectivity using Amazon Redshift ODBC driver

  2. Configure the connection:
    • Select dev-redshift from the Data source name.
    • Choose OK.
    • Complete Microsoft Entra ID authentication in your browser.
    Figure 24: Power bi desktop connectivity using Amazon Redshift odbc driver

    Figure 24: Power bi desktop connectivity using Amazon Redshift odbc driver

    Figure 25: Successful Microsoft Entra id authentication

    Figure 25: Successful Microsoft Entra id authentication

  3. Test the connection:
    • From Navigator, choose schema tpcds.
    • Select date_dim.
    • Choose Load.
    • Verify that you can analyze your Amazon Redshift data in Power BI Desktop.
    Figure26: Power BI desktop connected to Amazon Redshift and schema browsing

    Figure26: Power BI desktop connected to Amazon Redshift and schema browsing

    Figure 27: Power BI desktop fetching data from date_dim table

    Figure 27: Power BI desktop fetching data from date_dim table

Cleaning up

To avoid ongoing charges, delete the following resources:

  1. Delete the Amazon Redshift data warehouses (provisioned cluster or serverless workgroup and namespace) and the VPC endpoints that you created.
  2. Delete the certificate that you created in AWS Certificate Manager (ACM).
  3. Delete the Network Load Balancer.

Conclusion

In this post, we showed you how to integrate Amazon Redshift Serverless with Microsoft Entra ID using an AWS Network Load Balancer as a single connection endpoint across multiple workgroups. As your data analytics use cases grow, you can continue to scale horizontally by adding new workgroups behind the same Network Load Balancer without changing your users’ connection settings or authentication experience.

For more information about extending and scaling this solution, see the following resources:

AWS Blogs


About the authors

Raghu Kuppala

Raghu Kuppala

Raghu is an Analytics Specialist Solutions Architect experienced working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.

Raza Hafeez

Raza Hafeez

Raza is a Senior Product Manager at Amazon Redshift. He has over 13 years of professional experience building and optimizing enterprise data warehouses and is passionate about enabling customers to realize the power of their data. He specializes in migrating enterprise data warehouses to AWS Modern Data Architecture.

Harshida Patel

Harshida Patel

Harshida is a Analytics Specialist Principal Solutions Architect, with AWS.

Justin Chin-You

Justin Chin-You

Justin is a Solutions Architect at AWS, working with Financial Services organizations. He is helping these organizations identify the right cloud transformation strategy based on industry trends and their organizational priorities.

Designing centralized and distributed network connectivity patterns for Amazon OpenSearch Serverless – Part 2

Post Syndicated from Ankush Goyal original https://aws.amazon.com/blogs/big-data/designing-centralized-and-distributed-network-connectivity-patterns-for-amazon-opensearch-serverless-part-2/

This post is Part 2 of our two-part series on hybrid multi-account access patterns for Amazon OpenSearch Serverless. In Part 1, we explored a centralized architecture where a single account hosts multiple OpenSearch Serverless collections and a shared VPC endpoint. This approach works well when a single business unit or team manages collections on behalf of the organization.

However, many enterprises have multiple business units that need independent ownership of their OpenSearch Serverless infrastructure. When each business unit wants to manage their own collections, security policies, and VPC endpoints within their own AWS accounts, the centralized model from Part 1 no longer fits.

In this post, we address this multi-business unit scenario by introducing a pattern where the central networking account manages a custom private hosted zone (PHZ) with CNAME records pointing to each business unit’s VPC endpoint. This approach maintains centralized DNS management and connectivity while giving each business unit full autonomy over their collections and infrastructure.

The challenge with multiple business units

When multiple business units independently manage their own OpenSearch Serverless collections in separate AWS accounts, each account has its own VPC endpoint with its own private hosted zones. These private hosted zones only work within their respective VPCs, creating DNS fragmentation across the organization. Consumers in spoke accounts and on-premises environments can’t resolve collection endpoints in other accounts without additional DNS configuration.

Managing individual PHZ associations for each consumer VPC doesn’t scale, and asking each business unit to coordinate DNS with every consumer creates operational overhead. You need a network architecture that gives each team autonomy while keeping DNS management and connectivity centralized.

Solution overview

This architecture solves the problem by centralizing DNS management in the networking account while leaving collection and VPC endpoint ownership with each business unit. The networking account maintains a custom PHZ with CNAME records that map each collection endpoint to the regional DNS name of its corresponding VPC endpoint. This custom PHZ is associated with a Route 53 Profile and shared through AWS Resource Access Manager (AWS RAM) to spoke accounts. On-premises DNS resolution flows through the Route 53 Resolver inbound endpoint in the central networking VPC, which uses the same custom PHZ.

We cover two complementary patterns: Pattern 1 for on-premises access to collections across multiple business unit accounts, and Pattern 2 for spoke account access to those same collections. Both patterns rely on the centralized custom PHZ managed by your networking team.

Pattern 1: On-premises access to OpenSearch Serverless collections across multiple business unit accounts

With this pattern, your on-premises clients can privately access OpenSearch Serverless collections hosted across multiple business unit accounts, each with its own VPC endpoint. The following diagram illustrates this multi-business-unit architecture. It shows how on-premises DNS queries are resolved through the custom PHZ in the central networking account and routed to the correct business unit’s VPC endpoint through AWS PrivateLink.

(A) The Route 53 Profiles are created in the central networking account and shared through AWS Resource Access Manager (AWS RAM) with the central OpenSearch Serverless account.

(B) The central networking account has a custom PHZ with domain us-east-1.aoss.amazonaws.com and associated with central networking account VPC and with Route 53 Profiles.

(C) This PHZ contains CNAME records pointing to each business unit’s VPC endpoints.

(D) Each business unit account has Private DNS enabled on its VPC endpoint.

(E) This automatically creates the following PHZs during VPC endpoint creation and associates them with the business unit’s VPC, so DNS resolution works locally within that VPC without depending on the Route 53 Profiles.

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

DNS resolution flow

  1. Your on-premises client initiates a request to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com.
  2. The on-premises DNS resolver has a conditional forwarder for us-east-1.aoss.amazonaws.com and forwards the query over AWS Direct Connect or AWS Site-to-Site VPN to the Route 53 Resolver inbound endpoint IPs in the central networking VPC.
  3. The inbound Resolver endpoint passes the query to the Route 53 VPC Resolver in the central networking VPC.
  4. The VPC Resolver finds the custom PHZ (bu-1-collection-id-1.us-east-1.aoss.amazonaws.com) associated with the central networking VPC. The CNAME record for bu-1-collection-id-1.us-east-1.aoss.amazonaws.com resolves to the regional DNS name of BU1’s VPC endpoint (for example, vpce-1234567890abcdefghi.a2oselk.vpce-svc-0c3ebf9a1a3ad247b.us-east-1.vpce.amazonaws.com).
  5. The VPC Resolver then resolves the VPC endpoint regional DNS name to its elastic network interfaces (ENIs) private IP addresses.
  6. The traffic reaches BU1’s VPC endpoint elastic network interfaces (ENIs) through private network connectivity because the on-premises client connects over AWS Direct Connect or AWS Site-to-Site VPN through AWS Transit Gateway or AWS Cloud WAN.

Data flow

  1. Your on-premises client sends an HTTPS request to the resolved IP address with the TLS Server Name Indication (SNI) header set to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com, over AWS Direct Connect or AWS Site-to-Site VPN through AWS Transit Gateway or AWS Cloud WAN.
  2. Traffic reaches the VPC endpoint ENIs in BU1’s OpenSearch Serverless VPC.
  3. The VPC endpoint forwards the request to the OpenSearch Serverless service, which inspects the hostname and routes to BU1 Collection 1.

To access a collection in BU2, your client follows the same flow using bu-2-collection-id-1.us-east-1.aoss.amazonaws.com. The custom PHZ contains a separate CNAME record pointing to BU2’s VPC endpoint, and the OpenSearch Serverless service routes to the correct collection based on the hostname.

Pattern 2: Spoke account access to OpenSearch Serverless collections across multiple business unit accounts

While Pattern 1 addresses on-premises access, you might also need to provide access from compute resources and distributed applications in spoke accounts to OpenSearch Serverless collections across multiple business unit accounts. With this pattern, compute resources in spoke account VPCs can privately access OpenSearch Serverless collections across multiple business unit accounts through the centralized private hosted zone (PHZ) in the networking account.

In the following example, we use an Amazon Elastic Compute Cloud (Amazon EC2) instance as a compute resource to illustrate the pattern. However, the same approach applies to any compute resource within the spoke VPC. The following diagram illustrates this multi-business-unit, multi-spoke architecture, showing how spoke VPCs resolve DNS through the shared Route 53 Profile and custom PHZ, then route traffic to the correct business unit’s OpenSearch Serverless collections through AWS PrivateLink.

(A) The Route 53 Profiles, created in the central networking account, are shared through AWS RAM with all spoke accounts and with the central OpenSearch Serverless account.

(B) The central networking account has a custom PHZ with domain us-east-1.aoss.amazonaws.com and associated with central networking account VPC and with Route 53 Profiles.

(C) This PHZ contains CNAME records pointing to each business unit’s VPC endpoints.

(D) Each business unit account has Private DNS enabled on its VPC endpoint.

(E) This automatically creates the following PHZs during VPC endpoint creation and associates them with the business unit’s VPC, so DNS resolution works locally within that VPC without depending on the Route 53 Profiles.

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

DNS resolution flow

  1. An Amazon EC2 instance in BU1 Spoke VPC 1 initiates a request to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com and sends a DNS query to the Route 53 VPC Resolver.
  2. The VPC Resolver finds the Route 53 Profiles associated with the spoke VPC.
  3. The Profiles reference the custom PHZ (us-east-1.aoss.amazonaws.com) managed in the central networking account. The CNAME record for bu-1-collection-id-1.us-east-1.aoss.amazonaws.com resolves to the regional DNS name of BU1’s VPC endpoint.
  4. The VPC Resolver then resolves the VPC endpoint regional DNS name to its elastic network interfaces (ENIs) private IP addresses.
  5. Traffic reaches the VPC endpoint ENIs through private network connectivity because the spoke VPC connects to BU1’s VPC through AWS Transit Gateway or AWS Cloud WAN.

Data flow

  1. Your Amazon EC2 instance sends an HTTPS request to the resolved IP address with the TLS SNI header set to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com, routed through AWS Transit Gateway or AWS Cloud WAN to BU1’s OpenSearch Serverless VPC.
  2. The request arrives at the VPC endpoint ENIs in BU1’s OpenSearch Serverless VPC.
  3. The VPC endpoint forwards the request to the OpenSearch Serverless service, which inspects the hostname and routes to BU1 Collection 1.

To access a collection in BU2, the same flow applies using bu-2-collection-id-1.us-east-1.aoss.amazonaws.com. The custom PHZ resolves to BU2’s VPC endpoint, and routes traffic through the transit gateway to BU2’s VPC. The same applies to resources in other spoke accounts with the Route 53 Profiles associated.

Custom PHZ record structure

The custom PHZ in the central networking account uses the domain us-east-1.aoss.amazonaws.com and contains CNAME records that map each collection endpoint to the regional DNS name of its corresponding VPC endpoint. Note that collections within the same business unit account share the same VPC endpoint, so their CNAME records point to the same regional DNS name. Collections in different business unit accounts point to different VPC endpoints.

Custom PHZ management

Unlike Part 1, where the auto-created PHZs from the VPC endpoint handle DNS resolution, this pattern requires your networking team to manually maintain the custom PHZ. When a business unit adds a new collection, the networking team must add a corresponding CNAME record to the custom PHZ.

Cost considerations

The architecture patterns described in this post use several AWS services that can contribute to your overall costs, including Amazon Route 53 (hosted zones, DNS queries, and Resolver endpoints), and Route 53 Profiles. We recommend reviewing the official AWS pricing pages for the most current rates:

For a full cost estimate tailored to your workload, use the AWS Pricing Calculator.

Conclusion

In this post, we showed how you can give on-premises clients and spoke account resources private access to OpenSearch Serverless collections distributed across multiple business unit accounts. By centralizing DNS management through a custom PHZ in the networking account and sharing it through Route 53 Profiles, you avoid coordinating PHZ associations across accounts while giving each business unit full ownership of their collections and VPC endpoints.

Combined with Part 1, you now have two architectural approaches for hybrid multi-account access to OpenSearch Serverless: a centralized model where one account owns all collections and a shared VPC endpoint, and a distributed model where multiple business units each manage their own collections and VPC endpoints. Choose the centralized model when a single team manages collections on behalf of the organization. Choose the distributed model when business units need independent ownership of their OpenSearch Serverless infrastructure.

For additional details, refer to the Amazon OpenSearch Serverless VPC endpoint documentation and Route 53 Profiles documentation.


About the authors

Ankush Goyal

Ankush Goyal

Ankush is a Senior Technical Account Manager at AWS Enterprise Support, specializing in helping customers in the travel and hospitality industries optimize their cloud infrastructure. With over 20 years of IT experience, he focuses on leveraging AWS networking services to drive operational efficiency and cloud adoption. Ankush is passionate about delivering impactful solutions and enabling clients to streamline their cloud operations.

author name

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS. He specializes in guiding customers through the design, implementation, and support of AWS solutions. Combining his networking expertise with a drive to explore new technologies, he helps organizations successfully navigate their cloud journey. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Designing centralized and distributed network connectivity patterns for Amazon OpenSearch Serverless – Part 1

Post Syndicated from Ankush Goyal original https://aws.amazon.com/blogs/big-data/designing-centralized-and-distributed-network-connectivity-patterns-for-amazon-opensearch-serverless-part-1/

Amazon OpenSearch Serverless is a fully managed, serverless option for Amazon OpenSearch Service that removes the operational complexity of provisioning, configuring, and tuning OpenSearch clusters. When you run OpenSearch Serverless collections in a central account and need secure, private access from both on-premises environments and multiple AWS accounts, network architecture becomes critical. In this post, we explore two patterns to help you achieve this connectivity securely.

Solution overview

Working with customers implementing OpenSearch Serverless, we published blog posts addressing various network connectivity patterns to meet their evolving requirements:

In this post, we build on those patterns to address an additional enterprise requirement. When you manage many OpenSearch Serverless collections centrally but need access from multiple accounts and on-premises, you face several key challenges:

  • Coordinating VPC endpoints across accounts: managing endpoint provisioning and lifecycle across many consumer accounts adds operational overhead
  • Managing DNS configurations for each consumer: each new account or on-premises environment requires its own DNS setup, increasing complexity
  • Separating networking responsibilities from application ownership: without clear boundaries, networking and application teams become tightly coupled, slowing down both

This architecture solves these challenges with a clear separation of responsibilities. The central networking account shares Route 53 Profiles to manage DNS propagation across spoke accounts. The OpenSearch Serverless account owner maintains full control over their VPC endpoint and the associated private hosted zones (PHZs). Application owners retain autonomy over DNS configuration and collection management.

A single VPC endpoint handles multiple OpenSearch Serverless collections in an AWS Region, which reduces complexity and cost. Your networking team manages connectivity infrastructure while your application teams independently manage their OpenSearch Serverless collections, data access policies, and collection-specific DNS configurations. This gives you connectivity from on-premises networks (through AWS Direct Connect or AWS Site-to-Site VPN) and from compute resources across multiple AWS accounts through a unified network path.

This separation means that your network administrators and application teams can work independently. The result is a governance model that scales with your organization. We cover two complementary patterns that together give you complete hybrid access coverage, Pattern 1 for on-premises access and Pattern 2 for multi-account access, both using centralized interface VPC endpoints and Route 53 Profiles.

Before proceeding, you should be familiar with OpenSearch Serverless interface VPC endpoint DNS resolution. When creating an OpenSearch Serverless interface VPC endpoint, AWS automatically provisions four private hosted zones. The zones are three visible private hosted zones (for collections, dashboards, and FIPS endpoints) and one hidden internal private hosted zone that work together to resolve collection endpoints to private IP addresses. For more details on this DNS resolution mechanism, customers can review our previous blog post.

Pattern 1: Accessing multiple OpenSearch Serverless collections from on-premises through a centralized VPC endpoint and Route 53 Profiles in a multi-account architecture

The architecture spans three components:

  • A central OpenSearch Serverless account that hosts the collections and interface VPC endpoint.
  • A central networking account that owns the Route 53 Profiles and Inbound Resolver.
  • An on-premises environment connected using AWS Direct Connect or AWS Site-to-Site VPN.

The following diagram illustrates the architecture across these three components. It shows how DNS queries from on-premises clients are resolved through the Route 53 Profile and Inbound Resolver, and how data traffic reaches the OpenSearch Serverless collections using AWS PrivateLink.

(A) The Route 53 Profiles are created in the central networking account and shared through AWS Resource Access Manager (AWS RAM) with the central OpenSearch Serverless account. The central OpenSearch Serverless account associates the PHZs and interface VPC endpoint association with the shared Route 53 Profiles because that’s needed for end-to-end private DNS resolution.

(B) The central AOSS VPC contains an interface VPC endpoint for OpenSearch Serverless with Private DNS enabled. There are four Private Hosted Zones (PHZs):

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

(C) The first three PHZs must be manually associated with the Route 53 Profile.

(D) The fourth is automatically associated when the VPC endpoint is associated with the profile.

(E) On the on-premises side, the DNS resolver is configured with conditional forwarding for us-east-1.aoss.amazonaws.com, directing queries to the Route 53 Resolver Inbound Endpoint in the central networking account.

DNS resolution flow

  1. Your on-premises client initiates a request to collection-id-1.us-east-1.aoss.amazonaws.com.
  2. The on-premises DNS resolver has a conditional forwarder for us-east-1.aoss.amazonaws.com and forwards the query over AWS Direct Connect or AWS Site-to-Site VPN to the Route 53 Resolver inbound endpoint IPs in the central networking VPC.
  3. The inbound resolver receives the query and passes it to the Route 53 VPC Resolver.
  4. The VPC Resolver checks the Route 53 Profiles associated with the central networking VPC. The Profiles provide access to the visible and hidden PHZs from the central OpenSearch Serverless VPC.
  5. The VPC Resolver uses the visible PHZ to match the wildcard CNAME *.us-east-1.aoss.amazonaws.com to the interface VPC endpoint (VPCE) DNS name. It then uses the hidden PHZ to resolve the VPCE DNS name to the private elastic network interface (ENI) IP addresses of the interface VPC endpoint in the central OpenSearch Serverless VPC.
  6. The private ENI IP addresses are returned through the inbound resolver endpoint to the on-premises DNS resolver and back to the on-premises client.

Data flow

  1. The on-premises client sends an HTTPS request to the resolved private ENI IP address with the TLS Server Name Indication (SNI) header set to collection-id-1.us-east-1.aoss.amazonaws.com, over AWS Direct Connect or AWS Site-to-Site VPN through AWS Transit Gateway or AWS Cloud WAN.
  2. Traffic reaches the interface VPC endpoint ENIs in the central OpenSearch Serverless VPC.
  3. The interface VPC endpoint forwards the request to the OpenSearch Serverless service, which routes to Collection 1.

To access Collection 2, the client follows the same flow using collection-id-2.us-east-1.aoss.amazonaws.com. The wildcard DNS resolves to the same interface VPC endpoint, and the OpenSearch Serverless service routes to the correct collection based on the hostname.

Pattern 2: Accessing multiple OpenSearch Serverless collections from spoke accounts using a centralized VPC endpoint and Route 53 Profiles

While Pattern 1 addresses on-premises access, you might also need to provide access from compute resources and distributed applications across multiple AWS accounts. With this pattern, any compute resource running within spoke account VPCs can privately access multiple OpenSearch Serverless collections hosted in a central OpenSearch Serverless VPC through a single shared interface VPC endpoint.

In the following example, we use an Amazon Elastic Compute Cloud (Amazon EC2) instance as a compute resource to illustrate the pattern. However, the same approach applies to any compute resource within the spoke VPC.

The following diagram illustrates this multi-account architecture, showing how spoke account VPCs resolve DNS and route data traffic to the central OpenSearch Serverless collections through the shared Route 53 Profile and AWS PrivateLink, alongside the on-premises access path from Pattern 1.

(A) The Route 53 Profiles, created in the central networking account, are shared via AWS RAM with both the OpenSearch Serverless account and the spoke accounts. The OpenSearch Serverless account associates its interface VPC endpoint and private hosted zones (PHZs) with the Profiles, while each spoke account associates the Profiles with its VPC. Spoke VPCs get full DNS resolution for OpenSearch Serverless collection endpoints without requiring their own interface VPC endpoints, PHZs, or manual DNS configuration.

(B) The central AOSS VPC contains an interface VPC endpoint for OpenSearch Serverless with Private DNS enabled. There are four Private Hosted Zones (PHZs):

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

(C) The first three PHZs must be manually associated with the Route 53 Profile.

(D) The fourth is automatically associated when the VPC endpoint is associated with the profile.

DNS resolution flow

  1. An Amazon EC2 instance in Spoke VPC 1 initiates a request to collection-id-1.us-east-1.aoss.amazonaws.com and sends a DNS query to the Route 53 VPC Resolver.
  2. The VPC Resolver finds the Route 53 Profiles associated with the spoke VPC, which carries the PHZs from the central OpenSearch Serverless account.
  3. The visible PHZ matches the wildcard CNAME *.us-east-1.aoss.amazonaws.com to the VPCE DNS name. The hidden PHZ resolves the VPCE DNS name to the private ENI IP addresses of the interface VPC endpoint in the central OpenSearch Serverless VPC.
  4. Route 53 returns the private ENI IP addresses to the Amazon EC2 instance.

Data flow

  1. Your Amazon EC2 instance sends an HTTPS request to the resolved private ENI IP address with the TLS SNI header set to collection-id-1.us-east-1.aoss.amazonaws.com. This is routed through AWS Transit Gateway or AWS Cloud WAN to the central OpenSearch Serverless VPC.
  2. The request arrives at the interface VPC endpoint ENIs in the central OpenSearch Serverless VPC.
  3. The interface VPC endpoint forwards the request to the OpenSearch Serverless service, which routes to Collection 1.

To access Collection 2, the same flow applies using collection-id-2.us-east-1.aoss.amazonaws.com. The same applies to resources in Spoke Account 2 or other spoke accounts with the Route 53 Profiles associated.

AWS RAM Permission Configuration for Resource Association

When the central networking account shares the Route 53 Profiles through AWS RAM, the default AWS managed permissions policy (AWSRAMPermissionRoute53ProfileAllowAssociationActions) only grants actions for associating and disassociating the Profile with VPCs, viewing Profiles details, and listing associations. It does not include the route53profiles:AssociateResourceToProfile or route53profiles:DisassociateResourceFromProfile actions required for the OpenSearch Serverless account to associate its interface VPC endpoint and PHZs with the shared Profiles.

To enable this, the central networking account must create a custom managed permission in AWS RAM with the following actions:

  • route53profiles:AssociateProfile
  • route53profiles:AssociateResourceToProfile
  • route53profiles:DisassociateProfile
  • route53profiles:DisassociateResourceFromProfile
  • route53profiles:GetProfile
  • route53profiles:GetProfileResourceAssociation
  • route53profiles:ListProfileAssociations
  • route53profiles:ListProfileResourceAssociations
  • route53profiles:ListProfiles

This custom permission must be attached to the RAM resource share before the central OpenSearch Serverless account can associate its PHZs and interface VPC endpoint with the Profiles.

Cost considerations

The architecture patterns described in this post use several AWS services that may contribute to your overall costs, including Amazon Route 53 (hosted zones, DNS queries, and Resolver endpoints), and Route 53 Profiles. We recommend reviewing the official AWS pricing pages for the most current rates:

For a full cost estimate tailored to your workload, use the AWS Pricing Calculator.

Conclusion

In this post, we showed how organizations can provide secure, private access to multiple OpenSearch Serverless collections from both on-premises environments and distributed AWS accounts using a single centralized interface VPC endpoint and Route 53 Profiles. This architecture centralizes OpenSearch Serverless collections and network infrastructure in a dedicated account, using Route 53 Profiles to propagate DNS across accounts. This eliminates per-account VPC endpoints, manual PHZ associations, and custom DNS configuration in spoke accounts.

This pattern is a good fit when a single team or business unit manages OpenSearch Serverless collections centrally. However, many enterprises have business units that need to independently manage their own OpenSearch Serverless collections in separate AWS accounts, each with their own interface VPC endpoints, security policies, and collection lifecycle. In Part 2, we explore how the architecture changes to support this distributed ownership model, where each business unit runs OpenSearch Serverless in their own account while still relying on centralized network connectivity and DNS management through Route 53 Profiles. We will cover how DNS resolution and the Route 53 Profiles configuration adapt when interface VPC endpoints and collections are spread across multiple accounts.

For additional details, refer to the OpenSearch Serverless VPC endpoint documentation and Route 53 Profiles documentation.


About the authors

Ankush Goyal

Ankush Goyal

Ankush is a Senior Technical Account Manager at AWS Enterprise Support, specializing in helping customers in the travel and hospitality industries optimize their cloud infrastructure. With over 20 years of IT experience, he focuses on leveraging AWS networking services to drive operational efficiency and cloud adoption. Ankush is passionate about delivering impactful solutions and enabling clients to streamline their cloud operations.

author name

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS. He specializes in guiding customers through the design, implementation, and support of AWS solutions. Combining his networking expertise with a drive to explore new technologies, he helps organizations successfully navigate their cloud journey. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

AWS Weekly Roundup: Amazon S3 turns 20, Amazon Route 53 Global Resolver general availability, and more (March 16, 2026)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-s3-turns-20-amazon-route-53-global-resolver-general-availability-and-more-march-16-2026/

Twenty years ago this past week, Amazon S3 launched publicly on March 14, 2006. While Amazon Simple Storage Service is often considered the foundational storage service that defined cloud infrastructure, what began as a simple object storage service has grown into something far larger in scope and scale.

As of March 2026, S3 stores more than 500 trillion objects, serves more than 200 million requests per second globally across hundreds of exabytes of data, and the price has dropped to just over 2 cents per gigabyte — an approximately 85% reduction since launch. My colleague Sébastien Stormacq wrote a detailed look at the engineering and the road ahead in Twenty years of Amazon S3 and building what’s next, and if you want to read about those earliest customers and how they shaped what AWS became, I recommend How three startups helped Amazon invent cloud computing and paved the way for AI. Twenty years is worth pausing to celebrate.

Alongside the 20th anniversary of S3, Channy Yun also wrote about a new S3 feature this week: Account regional namespaces for Amazon S3 general purpose buckets. With this feature, you can create general purpose buckets in your own account regional namespace by appending your account’s unique suffix to your requested bucket name, ensuring your desired names are always reserved exclusively for your account. You can enforce adoption across your organization using AWS IAM policies and AWS Organizations service control policies with the new s3:x-amz-bucket-namespace condition key. Read Channy’s post to learn more about account regional namespaces for Amazon S3 general purpose buckets.

This week’s featured launch is one I have a personal connection to: the general availability of Amazon Route 53 Global Resolver. I wrote about the preview of this capability back in December at re:Invent 2025, and I had a great time putting that post together, so I am happy to hear that it’s generally available now.

Amazon Route 53 Global Resolver is an internet-reachable anycast DNS resolver that provides DNS resolution for authorized clients from any location. It is now generally available across 30 AWS Regions, with support for both IPv4 and IPv6 DNS query traffic. Route 53 Global Resolver gives authorized clients in your organization anycast DNS resolution of public internet domains and private domains associated with Route 53 private hosted zones — from any location, not just from within a specific VPC or Region. It also provides DNS query filtering to block potentially malicious domains, domains that are not safe for work, and domains associated with advanced DNS threats such as DNS tunneling and Domain Generation Algorithms (DGA). Centralized query logging is included as well. With general availability, Global Resolver adds protection against Dictionary DGA threats.

Last week’s launches
Here are some of the other announcements from last week:

  • Amazon Bedrock AgentCore Runtime now supports stateful MCP server features — Amazon Bedrock AgentCore Runtime now supports stateful Model Context Protocol (MCP) server features, enabling developers to build MCP servers that use elicitation, sampling, and progress notifications alongside existing support for resources, prompts, and tools. With stateful MCP sessions, each user session runs in a dedicated microVM with isolated resources, and the server maintains session context across multiple interactions using an Mcp-Session-Id header. Elicitation enables server-initiated, multi-turn conversations to gather structured input from users during tool execution. Sampling allows servers to request LLM-generated content from the client for tasks such as personalized recommendations. Progress notifications keep clients informed during long-running operations. To learn more, see the Amazon Bedrock AgentCore documentation.
  • Amazon WorkSpaces now supports Microsoft Windows Server 2025 — New bundles powered by Microsoft Windows Server 2025 are now available for Amazon WorkSpaces Personal and Amazon WorkSpaces Core. These bundles include security capabilities such as Trusted Platform Module 2.0 (TPM 2.0), Unified Extensible Firmware Interface (UEFI) Secure Boot, Secured-core server, Credential Guard, Hypervisor-protected Code Integrity (HVCI), and DNS-over-HTTPS. Existing Windows Server 2016, 2019, and 2022 bundles remain available. You can use the managed Windows Server 2025 bundles or create a custom bundle and image. This support is available in all AWS Regions where Amazon WorkSpaces is available. For more information, visit the Amazon WorkSpaces FAQs.
  • AWS Builder ID now supports Sign in with GitHub and Amazon — AWS Builder ID now supports two additional social login options: GitHub and Amazon. These options join the existing Google and Apple sign-in capabilities. With this update, developers can access their AWS Builder ID profile — and services including AWS Builder Center, AWS Training and Certification, and Kiro — using their existing GitHub or Amazon account credentials, without managing a separate set of credentials. To learn more and get started, visit the AWS Builder ID documentation.
  • Amazon Redshift introduces reusable templates for COPY operations — Amazon Redshift now supports templates for the COPY command, allowing you to store and reuse frequently used COPY parameters. Templates help maintain consistency across data ingestion operations, reduce the effort required to execute COPY commands, and simplify maintenance by applying template updates automatically to all future uses. Support for COPY templates is available in all AWS Regions where Amazon Redshift is available, including the AWS GovCloud (US) Regions. To get started, see the documentation or read the Standardize Amazon Redshift operations using Templates blog.

For a full list of AWS announcements, be sure to keep an eye on our News Blog channel the What’s New with AWS page.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

AWS Summits – Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).

AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include Pune (March 21), San Francisco (April 10), and Romania (April 23-24).

AWS at NVIDIA GTC 2026 — Join us at our AWS sessions, booths, demos, and ancillary events in NVIDIA GTC 2026 on March 16 – 19, 2026 in San Jose. You can receive 20% off event passes through AWS and request a 1:1 meeting at GTC.

AWS Community GameDay Europe — Taking place on March 17, 2026, AWS Community GameDay Europe is a team-based, hands-on AWS challenge event running simultaneously across 50+ cities in Europe. Your team is dropped into a broken AWS environment — misconfigured services, failing architectures, and security gaps — and has two hours to fix as much as possible. Find your nearest city and sign up at awsgameday.eu.

Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Introducing Amazon Route 53 Global Resolver for secure anycast DNS resolution (preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/introducing-amazon-route-53-global-resolver-for-secure-anycast-dns-resolution-preview/

Today, we’re announcing Amazon Route 53 Global Resolver, a new Amazon Route 53 service that provides secure and reliable DNS resolution globally for queries from anywhere (preview). You can use Global Resolver to resolve DNS queries to public domains on the internet and private domains associated with Route 53 private hosted zones. Route 53 Global Resolver offers network administrators a unified solution to resolve queries from authenticated clients and sources in on-premises data centers, branch offices, and remote locations through globally distributed anycast IP addresses. This service includes built-in security controls including DNS traffic filtering, support for encrypted queries, and centralized logging to help organizations reduce operational overhead while maintaining compliance with security requirements.

Organizations with hybrid deployments face operational complexity when managing DNS resolution across distributed environments. Resolving public internet domains and private application domains often requires maintaining split DNS infrastructure, which increases cost and administrative burden especially when replicating to multiple locations. Network administrators must configure custom forwarding solutions, deploy Route 53 Resolver endpoints for private domain resolution, and implement separate security controls across different locations. Additionally, they must configure and maintain multi-Region failover strategies for Route 53 Resolver endpoints and provide consistent security policy enforcement across all Regions while testing failover scenarios.

Route 53 Global Resolver has key capabilities that address these challenges. The service resolves both public internet domains and Route 53 private hosted zones, eliminating the need for separate split-DNS forwarding. It provides DNS resolution through multiple protocols, including DNS over UDP (Do53), DNS-over-HTTPS (DoH), and DNS-over-TLS (DoT). Each deployment provides a single set of common IPv4 and IPv6 anycast IP addresses that route queries to the nearest AWS Region, reducing latency for distributed client populations.

Route 53 Global Resolver provides integrated security features equivalent to Route 53 Resolver DNS Firewall. Administrators can configure filtering rules using AWS Managed Domain Lists that provide flexible controls with lists classified by DNS threats (malware, spam, phishing) or web content (adult sites, gambling, social networking) that might not be safe for work or create custom domain lists by importing domains from a file. Advanced threat protection detects and blocks domain generation algorithm (DGA) patterns and DNS tunneling attempts. For encrypted DNS traffic, Route 53 Global Resolver supports DoH and DoT protocols to protect queries from unauthorized access during transit.

Route 53 Global Resolver only accepts traffic from known clients that need to authenticate with the Resolver. For Do53, DoT, and DoH connections, administrators can configure IP and CIDR allowlists. For DoH and DoT connections, token-based authentication provides granular access control with customizable expiration periods and revocation capabilities. Administrators can assign tokens to specific client groups or individual devices based on organizational requirements.

Route 53 Global Resolver supports DNSSEC validation to verify the authenticity and integrity of DNS responses from public nameservers. It also includes EDNS Client Subnet support, which forwards client subnet information to enable more accurate geographic-based DNS responses from content delivery networks.

Getting started with Route 53 Global Resolver
This walkthrough shows how to configure Route 53 Global Resolver for an organization with offices on the US East and West coasts that needs to resolve both public domains and private applications hosted in Route 53 private hosted zones. To configure Route 53 Global Resolver, go to the AWS Management Console, choose Global resolvers from the navigation pane, and choose Create global resolver.

In the Resolver details section, enter a Resolver name such as corporate-dns-resolver. Add an optional description like DNS resolver for corporate offices and remote clients. In the Regions section, choose the AWS Regions where you want the resolver to operate, such as US East (N. Virginia) and US West (Oregon). The anycast architecture routes DNS queries from your clients to the nearest selected Region.

After the resolver is created, the console displays the resolver details, including the anycast IPv4 and IPv6 addresses that you will use for DNS queries. You can proceed to create a DNS view by choosing Create DNS view to configure client authentication and DNS query resolution settings.

In the Create DNS view section, enter a DNS view name such as primary-view and optionally add a Description like DNS view for corporate offices. A DNS view helps you create different logical groupings for your clients and sources, and determine the DNS resolution for those groups. This helps you maintain different DNS filtering rules and private hosted zone resolution policies for different clients in your organization.

For DNSSEC validation, choose Enable to verify the authenticity of DNS responses from public DNS servers. For Firewall rules fail open behavior, choose Disable to block DNS queries when firewall rules can’t be evaluated, which provides additional security. For EDNS client subnet, keep Enable selected to forward client location information to DNS servers, which allows content delivery networks to provide more accurate geographic responses. DNS view creation might take a few minutes to become operational.

After the DNS view is created and operational, configure DNS Firewall rules to filter network traffic by choosing Create rule. In the Create DNS Firewall rules section, enter a Rule name such as block-malware-domains and optionally add a description. For Rule configuration type, you can choose Customer managed domain lists, AWS managed domain lists provided by AWS or DNS Firewall Advanced protection.

For this walkthrough, choose AWS managed domain lists. In the Domain lists dropdown, choose one or more AWS managed lists such as Threat – Malware to block known malicious domains. You can leave Query type empty to apply the rule to all DNS query types. In this example, choose A to apply this rule only to IPv4 address queries. In the Rule action section, select Block to prevent DNS resolution for domains that match the selected lists. For Response to send for Block action, keep NODATA selected to indicate that the query was successful but no response is available, then choose Create rules.

The next step is to configure access sources to specify which IP addresses or CIDR blocks are allowed to send DNS queries to the resolver. Navigate to the Access sources tab in the DNS view and then choose Create access source.

In the Access source details section, enter a Rule name such as office-networks to identify the access source. In the CIDR block field, enter the IP address range for your offices to allow queries from that network. For Protocol, select Do53 for standard DNS queries over UDP or choose DoH or DoT if you want to require encrypted DNS connections from clients. After configuring these settings, choose Create access source to allow the specified network to send DNS queries to the resolver.

Next, navigate to the Access tokens tab in the DNS view to create token-based authentication for clients and choose Create access token. In the Access token details section, enter a Token name such as remote-clients-token. For Token expiry, select an expiration period from the dropdown based on your security requirements, such as 365 days for long-term client access, or choose a shorter duration like 30 days or 90 days for tighter access control. After configuring these settings, choose Create access token to generate the token, which clients can use to authenticate DoH and DoT connections to the resolver.

After the access token is created, navigate to the Private hosted zones tab in the DNS view to associate Route 53 private hosted zones with the DNS view so that the resolver can resolve queries for your private application domains. Choose Associate private hosted zone and in the Private hosted zones section, select a private hosted zone from the list that you want the resolver to handle. After selecting the zone, choose Associate to enable the resolver to respond to DNS queries for these private domains from your configured access sources.

With the DNS view configured, firewall rules created, access sources and tokens defined, and private hosted zones associated, the Route 53 Global Resolver setup is complete and ready to handle DNS queries from your configured clients.

After creating your Route 53 Global Resolver, you need to configure your DNS clients to send queries to the resolver’s anycast IP addresses. The configuration method depends on the access control you configured in your DNS view:

  • For IP-based access sources (CIDR blocks) – Configure your source clients to point DNS traffic to the Route 53 Global Resolver anycast IP addresses provided in the resolver details. Global Resolver will only allow access from allowlisted IPs that you have specified in your access sources. You can also associate the access sources to different DNS views to provide more granular DNS resolution views for different sets of IPs.
  • For access token–based authentication – Deploy the tokens on your clients to authenticate DoH and DoT connections with Route 53 Global Resolver. You must also configure your clients to point the DNS traffic to the Route 53 Global Resolver anycast IP addresses provided in the resolver details.

For detailed configuration instructions for your specific operating system and protocol, refer to the technical documentation.

Additional things to know
We’re renaming the existing Route 53 Resolver to Route 53 VPC Resolver. This naming change clarifies the architectural distinction between the two services. VPC Resolver operates Regionally within your VPCs to provide DNS resolution for resources in your Amazon VPC environment. VPC Resolver continues to support inbound and outbound resolver endpoints for hybrid DNS architectures within specific AWS Regions.

Route 53 Global Resolver complements Route 53 VPC Resolver by providing internet-reachable, global and private DNS resolution for on-premises and remote clients without requiring VPC deployment or private connections.

Existing VPC Resolver configurations remain unchanged and continue to function as configured. The renaming affects the service name in the AWS Management Console and documentation, but API operation names remain unchanged. If your architecture requires DNS resolution for resources within your VPCs, continue using VPC Resolver.

Join the preview
Route 53 Global Resolver reduces operational overhead by providing unified DNS resolution for public and private domains through a single managed service. The global anycast architecture improves reliability and reduces latency for distributed clients. Integrated security controls and centralized logging help organizations maintain consistent security policies across all locations while meeting compliance requirements.

To learn more about Amazon Route 53 Global Resolver, visit the Amazon Route 53 documentation.

You can start using Route 53 Global Resolver through the AWS Management Console in US East (N. Virginia), US East (Ohio), US West (N. California), US West (Oregon), Europe (Frankfurt), Europe (Ireland), Europe (London), Asia Pacific (Mumbai), Asia Pacific (Singapore), Asia Pacific (Tokyo), and Asia Pacific (Sydney) Regions.

— Esra

Amazon Route 53 launches Accelerated recovery for managing public DNS records

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/amazon-route-53-launches-accelerated-recovery-for-managing-public-dns-records/

Today, we’re announcing Amazon Route 53 Accelerated recovery for managing public DNS records, a new Domain Name Service (DNS) business continuity feature that is designed to provide a 60-minute recovery time objective (RTO) during service disruptions in the US East (N. Virginia) AWS Region. This enhancement ensures that customers can continue making DNS changes and provisioning infrastructure even during regional outages, providing greater predictability and resilience for mission-critical applications.

Customers running applications that require business continuity have told us they need additional DNS resilience capabilities to meet their business continuity requirements and regulatory compliance obligations. While AWS maintains exceptional availability across our global infrastructure, organizations in regulated industries like banking, FinTech, and SaaS want the confidence that they will be able to make DNS changes even during unexpected regional disruptions, allowing them to quickly provision standby cloud resources or redirect traffic when needed.

Accelerated recovery for managing public DNS records addresses this need by targeting DNS changes that customers can make within 60 minutes of a service disruption in the US East (N. Virginia) Region. The feature works seamlessly with your existing Route 53 setup, providing access to key Route 53 API operations during failover scenarios, including ChangeResourceRecordSets, GetChange, ListHostedZones, and ListResourceRecordSets. Customers can continue using their existing Route 53 API endpoint without modifying applications or scripts.

Let’s try it out
Configuring a Route53 hosted zone to use accelerated recovery is simple. Here I am creating a new hosted zone for a new website I’m building.

Once I have created my hosted zone, I see a new tab labeled Accelerated recovery. I can see here that accelerated recovery is disabled by default.

To enable it, I just need to click the Enable button and confirm my choice in the modal that appears as depicted in the dialog below.

Enabling accelerated recovery will take a couple minutes to complete. Once it’s enabled, I see a green Enabled status as depicted in the screenshot below.

I can disable accelerated recovery at any time from this same area of the AWS Management Console. I can also enable accelerated recovery for any existing hosted zones I have already created.

Enhanced DNS business continuity
With accelerated recovery enabled, customers gain several key capabilities during service disruptions. The feature maintains access to essential Route 53 API operations, ensuring that DNS management remains available when it’s needed most. Organizations can continue to make critical DNS changes, provision new infrastructure, and redirect traffic flows without waiting for full service restoration.

The implementation is designed for simplicity and reliability. Customers don’t need to learn new APIs or modify existing automation scripts. The same Route 53 endpoints and API calls continue to work, providing a seamless experience during both normal operations and failover scenarios.

Now available
Accelerated recovery for Amazon Route 53 public hosted zones is available now. You can enable this feature through the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS Software Development Kit (AWS SDKs), or infrastructure as code tools like AWS CloudFormation and AWS Cloud Development Kit (AWS CDK). There is no additional cost for using accelerated recovery.

To learn more about accelerated recovery and get started, visit the documentation. This new capability represents our continued commitment to providing customers with the DNS resilience they need to build and operate mission-critical applications in the cloud.

AWS Weekly Roundup: Project Rainier, Amazon CloudWatch investigations, AWS MCP servers, and more (June 30, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-project-rainier-amazon-cloudwatch-investigations-aws-mcp-servers-and-more-june-30-2025/

Every time I visit Seattle, the first thing that greets me at the airport is Mount Rainier. Did you know that the most innovative project at Amazon Web Services (AWS) is named after this mountain?

Project Rainier is a new project to create what is expected to be the world’s most powerful computer for training AI models across multiple data centers in the United Stages. Anthropic will develop the advanced versions of its Claude models with five times more computing power than its current largest training cluster.

The key technology powering Project Rainier is AWS custom-designed Trainium2 chips, which are specialized for the immense data processing required to train complex AI models. Thousands of these Trainium2 chips will be connected in a new type of Amazon EC2 UltraServer and EC2 UltraCluster architecture that allows ultra-fast communication and data sharing across the massive system.

Learn about the AWS vertical integration of Project Rainer, where it designs every component of the technology stack from chips to software, allows it to optimize the entire system for maximum efficiency and reliability.

Last week’s launches
Here are some launches that got my attention:

  • Amazon S3 access for Amazon FSx for OpenZFS – You can access and analyze your FSx for OpenZFS file data through Amazon S3 Access Points, enabling seamless integration with AWS AI/ML, and analytics services without moving your data out of the file system. You can treat your FSx for OpenZFS data as if it were stored in S3, making it accessible through the S3 API for various applications including Amazon Bedrock, Amazon SageMaker, AWS Glue, and other S3 based cloud-native applications.
  • Amazon S3 with sort and z-order compaction for Apache Iceberg tables – You can optimize query performance and reduce costs with new sort and z-order compaction. With S3 Tables, sort compaction automatically organizes data files based on defined column orders, while z-order compaction can be enabled through the maintenance API for efficient multicolumn queries.
  • Amazon CloudWatch investigations – You can accelerate your operational troubleshooting in AWS environments using the Amazon CloudWatch AI-powered investigation feature, which helps identify anomalies, surface related signals, and suggest remediation steps. This capability can be initiated through CloudWatch data widgets, multiple AWS consoles, CloudWatch alarm actions, or Amazon Q chat and enables team collaboration and integration with Slack and Microsoft Teams.
  • Amazon Bedrock Guardrails Standard tier – You can enhance your AI content safety measures using the new Standard tier. It offers improved content filtering and topic denial capabilities across up to 60 languages, better detection of variations including typos, and stronger protection against prompt attacks. This feature lets you configure safeguards to block harmful content, prevent model hallucinations, redact personally identifiable information (PII), and verify factual claims through automated reasoning checks.
  • Amazon Route 53 Resolver endpoints for private hosted zone – You can simplify DNS management across AWS and on-premises infrastructure using the new Route 53 DNS delegation feature for private hosted zone subdomains, which works with both inbound and outbound Resolver endpoints. You can delegate subdomain authority between your on-premises infrastructure and Route 53 Resolver cloud service using name server records, eliminating the need for complex conditional forwarding rules.
  • Amazon Q Developer CLI for Java transformation – You can automate and scale Java application upgrades using the new Amazon Q Developer Java transformation command line interface (CLI). This feature perform upgrades from Java versions 8, 11, 17, or 21 to versions 17 or 21 directly from the command line. This tool offers selective transformation options so you can choose specific steps from transformation plans and customize library upgrades.
  • New AWS IoT Device Management managed integrations – You can simplify Internet of Things (IoT) device management across multiple manufacturers and protocols using the new managed integrations feature, which provides a unified interface for controlling devices whether they connect directly, through hubs or third-party clouds. The feature includes pre-built cloud-to-cloud (C2C) connectors, device data model templates, and SDKs that support ZigBee, Z-Wave, and Wi-Fi protocols, while you can still create custom connectors and data models.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Various Model Context Protocol (MCP) servers for AWS services have been released. Here are some tutorials about MCP servers that you might find interesting:

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. If you’re an early-career professional, you can apply to the All Builders Welcome Grant program, which is designed to remove financial barriers and create diverse pathways into cloud technology.
  • AWS NY Summits – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Channy

Amazon Bedrock baseline architecture in an AWS landing zone

Post Syndicated from Abdel-Rahman Awad original https://aws.amazon.com/blogs/architecture/amazon-bedrock-baseline-architecture-in-an-aws-landing-zone/

As organizations increasingly adopt Amazon Bedrock to build and deploy large-scale AI applications, it’s important that they understand and adopt critical network access controls to protect their data and workloads. These generative AI-enabled applications might have access to sensitive or confidential information within their knowledge bases, Retrieval Augmented Generation (RAG) data sources, or models themselves, which could pose a risk if exposed to unauthorized parties. Additionally, organizations might want to limit access to certain AI models to specific teams or services, making sure only authorized users can use the most powerful capabilities. Another important consideration is cost optimization, because organizations need to be able to monitor and control access to manage various aspects of their cloud spending.

In this post, we explore the Amazon Bedrock baseline architecture and how you can secure and control network access to your various Amazon Bedrock capabilities within AWS network services and tools. We discuss key design considerations, such as using Amazon VPC Lattice auth policies, Amazon Virtual Private Cloud (Amazon VPC) endpoints, and AWS Identity and Access Management (IAM) to restrict and monitor access to your Amazon Bedrock capabilities.

By the end of this post, you will have a better understanding of how to configure your AWS landing zone to establish secure and controlled network connectivity to Amazon Bedrock across your organization using VPC Lattice.

Solution overview

Addressing the aforementioned challenges requires a well-designed network architecture and security controls. For this, we use the standard AWS Landing Zone Accelerator networking configuration. It provides a good starting point for managing network communication across multiple accounts. On top of the AWS Landing Zone Accelerator network design, we add two shared accounts.

In this solution design, we create a centralized architecture for managing organization AI capabilities across different accounts. The architecture consists of three main parts that work together to provide secure and controlled access to AI services:

  • Service network account – This account serves as the central networking hub for the organization, managing network connectivity and access policies. Through this account, network administrators can centrally manage and control access to AI services across the organization. The account follows AWS Landing Zone Accelerator networking practices that scale with enterprise organizational needs.
  • Generative AI account – This account hosts the organization’s Amazon Bedrock capabilities and serves as the central point for AI/ML management. The organization’s AI/ML scientists and prompt engineers will centrally build and manage Amazon Bedrock capabilities. The account provides access to various large language models (LLMs) through Amazon Bedrock by using VPC interface endpoints, while also enabling centralized monitoring of cost consumption and access patterns.
  • Workload accounts (dev, test, prod) – These accounts represent different environments where teams develop and deploy applications that consume AI services. Through secure network connections established through the service network account, these workload accounts can access the AI capabilities hosted in the generative AI account. This separation enforces proper isolation between development, testing, and production workloads while maintaining secure access to AI services.
Amazon Bedrock baseline architecture in an AWS landing zone

Amazon Bedrock baseline architecture in an AWS landing zone

The following diagram illustrates the solution architecture.

The service network account has its own VPC Lattice service network—a centralized networking construct that enables service-to-service communication across your organization, which is shared with workload accounts using AWS Resource Access Manager (AWS RAM) to enable VPC Lattice Service network sharing.

Workload accounts (dev, test, prod) establish VPC associations with the shared VPC Lattice service network by creating a service network association in their VPC. When an application in these accounts makes a request, it first queries the VPC resolver for DNS resolution. The resolver routes the traffic to the VPC Lattice service network.

Access control is implemented through an VPC Lattice auth policy. The service network policies determine which accounts can access the VPC Lattice service network, and service-level policies control access to specific AI services and define what actions each account can perform.

In the central AI services account, we find the proxy layer, we create a VPC Lattice service that points to a proxy layer, which acts as a single entry point, providing workload accounts access to Amazon Bedrock. This proxy layer then connects to Amazon Bedrock through VPC endpoints. Through this setup, the AI team can configure which foundation models (FMs) are available and manage access permissions for different workload accounts. After the necessary policies and connections are in place, workload accounts can access Amazon Bedrock capabilities through the established secure pathway. This setup enables secure, cross-account access to AI services while maintaining centralized control and monitoring.

Network components

We use VPC Lattice, which is a fully managed application networking service that helps you simplify network connectivity, security, and monitoring for service-to-service communication needs. With VPC Lattice, organizations can achieve a centralized connectivity pattern to control and monitor access to the services required for building generative AI applications.

For details about VPC Lattice, refer to the Amazon VPC Lattice User Guide. The following is an overview of the constructs you can use in setting up the centralized pattern in this solution:

  • VPC Lattice service network – You can use the VPC Lattice service network to provide central connectivity and security to the central AI services account. The service network is a logical grouping mechanism that simplifies how you can enable connectivity across VPCs or accounts, and apply common security policies for application communication patterns. You can create a service network in an account and share it with other accounts within or outside AWS Organizations using AWS RAM.
  • VPC Lattice service – In a service network, you can associate a VPC Lattice service, which consists of a listener (protocol and port number), routing rules that allow for control of the application flow (for example, path, method, header-based, or weighted routing), and target group, which defines the application infrastructure. A service can have multiple listeners to meet various client capabilities. Supported protocols include HTTP, HTTPS, gRPC, and TLS. The path-based routing allows control to various high-performing FMs and other capabilities you would need to build a generative AI application.
  • Proxy layer – You use a proxy layer for the VPC Lattice service target group. The proxy layer can be built based on your organization’s preference of AWS services, such as AWS Lambda, AWS Fargate, or Amazon Elastic Kubernetes Service (Amazon EKS). The purpose of the proxy layer is to provide a single entry point to access LLMs, knowledge bases, and other capabilities that are tested and approved according to your organization’s compliance requirements.
  • VPC Lattice auth policies – For security, you use VPC Lattice auth policies. VPC Lattice auth policies are specified using the same syntax as IAM policies. You can apply an auth policy to VPC Lattice service network as well as to the VPC Lattice service.
  • Fully Qualified Domain Names –To facilitate service discovery, VPC Lattice supports custom domain names for your services and resources, and maintains a Fully Qualified Domain Name (FQDN) for each VPC Lattice service and resource you define. You can use these FQDNs in your Amazon Route 53 private hosted zone configurations, and empower business units or teams to discover and access services and resources.
  • Service network VPC – Business units or teams can access generative AI services in a service network using service network VPC associations or a service network VPC endpoint.
  • Monitoring – You can choose to enable monitoring at the VPC Lattice service network level and VPC Lattice service level. VPC Lattice generates metrics and logs for requests and responses, making it more efficient to monitor and troubleshoot applications

The preceding guidance takes a “secure by default” approach—you must be explicit about which features, models, and so on should be accessed by which business unit. The setup also enables you to implement a defense-in-depth strategy at multiple layers of the network:

  • The first level of defense is that business team needs to connect to the service network in order to get access to the generative AI service through the central AI service account.
  • The second level includes network-level security protections in the business team’s VPC for the service network, such as security groups and network access control lists (ACLs). By using these, you can allow access to specific workloads or teams in a VPC.
  • The third level is through the VPC Lattice auth policy, which you can apply at two layers: at the service network level to allow authenticated requests within the organization, and at the service level to allow access to specific models and features.

VPC Lattice auth policy

This solution makes it possible to centrally manage access to Amazon Bedrock resources across your organization. This approach uses an VPC Lattice auth policy to centrally control Amazon Bedrock resources and manage it from one location across all the organization accounts.

Typically, the auth policy on the service network is operated by the network or cloud administrator. For example, allowing only authenticated requests from specific workloads or teams in your AWS organization. In the following example, access is granted to invoke the generated AI service for authenticated requests and to principals that are part of the o-123456example organization:

{
   "Version": "2012-10-17",
   "Statement": [
      {
         "Effect": "Allow",
         "Principal": "*",
         "Action": "vpc-lattice-svcs:Invoke",
         "Resource": "*",
         "Condition": {
            "StringEquals": {
               "aws:PrincipalOrgID": [ 
                  "o-123456example"
               ]
            }
         }
      }
   ]
}

The auth policy at the service level is managed by the central AI service team to set fine-grained controls, which can be more restrictive than the coarse-grained authorization applied at the service network level. For example, the following policy restricts access to claude-3-haiku for only business-team1:

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Effect": "Allow",
         "Principal": {
            "AWS": [
               "arn:aws:iam::<account-number>:role/businss-team1"
            ]
         },
         "Action": "vpc-lattice-svcs:Invoke",
         "Resource": [
            "arn:aws:vpc-lattice:<aws-region>:<account-number>:service/svc-0123456789abcdef0/*"
         ],
         "Condition": {
            "StringEquals": {
               "vpc-lattice-svcs:RequestQueryString/modelid": "claude-3-haiku"            }
         }
      }
   ]
}

Monitoring and tracking

This design employs three monitoring approaches, using Amazon CloudWatch, AWS CloudTrail, and VPC Lattice access logs. This strategy provides a view of service usage, security, and performance.

CloudWatch metrics offer real-time monitoring of VPC Lattice service performance and usage. CloudWatch tracks metrics such as request counts and response times for Amazon Bedrock related endpoints, allowing for the setup of alarms for proactive management of service health and capacity. This enables monitoring of overall usage patterns of Amazon Bedrock models across different business units, facilitating capacity planning and resource allocation. CloudTrail provides detailed API-level auditing of Amazon Bedrock related actions. It logs cross-account access attempts and interactions with Amazon Bedrock services, providing a compliance and security audit trail. This tracking of who is accessing which Amazon Bedrock models, when, and from which accounts helps organizations adhere to their organizational policies.VPC Lattice access logs provide detailed insights into HTTP/HTTPS requests to Amazon Bedrock services, capturing specific usage patterns of AI models by different business teams. These logs contain client-specific information, which for example can be used to enable organizations to implement capabilities such as charge-back models. This allows for accurate attribution of AI service usage to specific teams or departments, facilitating fair cost allocation and responsible resource utilization across the organization. These services work together to enhance security, optimize performance, and provide valuable insights for managing cross-account Amazon Bedrock access.

Conclusion

In this post, we explored the importance of securing and controlling network access to Amazon Bedrock capabilities within an organization’s AWS landing zone. We discussed the key business challenges, such as the need to protect sensitive information in Amazon Bedrock knowledge bases, limit access to AI models, and optimize cloud costs by monitoring and controlling Amazon Bedrock capabilities. To address these challenges, we outlined a multi-layered network solution that uses AWS networking services, including a VPC Lattice auth policy to restrict and monitor access to Amazon Bedrock capabilities. Try out this solution for your own use case, and share your feedback in the comments.


About the authors

Designing centralized and distributed network connectivity patterns for Amazon OpenSearch Serverless

Post Syndicated from Ankush Goyal original https://aws.amazon.com/blogs/big-data/designing-centralized-and-distributed-network-connectivity-patterns-for-amazon-opensearch-serverless/

Amazon OpenSearch Serverless is a fully managed search and analytics service that automatically provisions and scales infrastructure to help you run search and analytics workloads without cluster management. With OpenSearch Serverless, you can quickly build search and analytics capabilities into your applications.

As organizations scale their use of OpenSearch Serverless, understanding network architecture and DNS management becomes increasingly important. Building upon the connectivity patterns discussed in our previous post Network connectivity patterns for Amazon OpenSearch Serverless, this post covers advanced deployment scenarios focused on centralized and distributed access patterns—specifically, how enterprises can simplify network connectivity across multiple AWS accounts and extend access to on-premises environments for their OpenSearch Serverless deployments.

We outline two key deployment patterns:

  • Pattern 1 – A centralized endpoint model where interface virtual private cloud (VPC) endpoints for OpenSearch Serverless are deployed in a shared services VPC, allowing spoke VPCs from other AWS accounts and on premises to access OpenSearch Serverless collections through these consolidated endpoints.
  • Pattern 2 – A distributed endpoint model where interface VPC endpoints are created in individual spoke VPCs, with multiple consumers (central account, on-premises networks, and other spoke accounts) accessing these endpoints through centralized DNS management. This approach provides direct connectivity within each spoke VPC while maintaining centralized DNS control and management across the organization.

Before diving into advanced deployment patterns, let’s review the DNS behavior of OpenSearch Serverless when accessed through an interface VPC endpoint (AWS PrivateLink). Understanding this foundational aspect can help clarify the connectivity patterns we explore in this post.

OpenSearch Serverless interface VPC endpoint DNS resolution

When creating an OpenSearch Serverless interface VPC endpoint, the service automatically provisions three private hosted zones: one visible private hosted zone us-east-1.aoss.amazonaws.com that handles domain resolution for the OpenSearch Serverless collection and dashboard, another visible private hosted zone us-east-1.opensearch.amazonaws.com that manages resolution for the OpenSearch UI (OpenSearch Dashboards), and one hidden internal private hosted zone that manages the final DNS resolution to private IP addresses.

Our objective in this post is to explore how the two private hosted zones for OpenSearch Serverless work together: the visible private hosted zone us-east-1.aoss.amazonaws.com for collections and dashboards, and the hidden private hosted zone for final DNS resolution to private IP addresses. We examine how these private hosted zones enable scalable DNS resolution in both centralized and distributed architectures. The following workflow diagram shows the DNS resolution flow for the us-east-1 AWS Region. The same pattern applies to other Regions, with the Region identifiers in the DNS records changing accordingly.

DNS Workflow Diagram AOSS

The workflow consists of the following steps:

  1. A user requests access to a collection URL (for example, abc.us-east-1.aoss.amazonaws.com).
  2. The DNS request is sent to the Amazon Route 53 Resolver, which checks the visible private hosted zone us-east-1.aoss.amazonaws.com and finds a CNAME record pointing to the endpoint-specific domain.
  3. The Route 53 Resolver uses the hidden internal private hosted zone to resolve this endpoint-specific domain to the VPC endpoint’s private IP address.
  4. Traffic is allowed only if it originates from the interface VPC endpoint approved by OpenSearch Serverless network policies.

Although this DNS Resolution Process provides flexible and secure private access, it becomes complex when you need connectivity from multiple VPCs, different AWS accounts, or on-premises networks. The following patterns address these challenges and outline strategies to simplify network access and DNS management for OpenSearch Serverless in such environments.

Pattern 1: Centralized interface VPC endpoint for OpenSearch Serverless

This pattern uses a centralized approach where a shared services AWS account with a shared services VPC hosts the OpenSearch Serverless interface VPC endpoint and OpenSearch Serverless collection. From there, other AWS accounts with Amazon VPCs (spoke VPCs) need to be able to access OpenSearch Serverless collections through this central endpoint. Organizations commonly implement this setup in hub-and-spoke network designs that connect their VPCs using either AWS Transit Gateway or AWS Cloud WAN. The following diagram illustrates this architecture.

AOSS Centralized Account

Challenge

When accessing from on-premises networks, both network access and DNS resolution for the OpenSearch Serverless interface VPC endpoint work successfully. However, although the endpoint is network-accessible from spoke VPCs (for example, through Transit Gateway or AWS Cloud WAN), DNS resolution from these VPCs fail.

This happens because OpenSearch Serverless creates and uses a private hosted zone us-east-1.aoss.amazonaws.com that is only associated with the VPC containing the endpoint, in this case, the Shared Services VPC. Simply sharing this private hosted zone with the spoke VPCs doesn’t solve the problem, because the wildcard CNAME record references a DNS name privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev. This DNS name can’t be resolved from other VPCs without additional configuration, because it belongs to a private hosted zone privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev that is only associated with the shared services VPC. This private hosted zone isn’t visible in your account and is controlled by AWS.

Solution: Use Amazon Route 53 Profiles for cross-VPC DNS resolution

To enable centralized DNS resolution, you can use Amazon Route 53 Profiles. With Route 53 Profiles, you can manage and apply DNS-related Amazon Route 53 configurations across multiple VPCs and AWS accounts. The following diagram illustrates the solution architecture.

AOSS Centralized Account Route53 Profile

The solution consists of the following steps:

  1. Create an OpenSearch Serverless interface VPC endpoint in the shared services VPC. This automatically creates and associates the following:
      1. Two default private hosted zones.
      2. One hidden private hosted zone with this VPC.
  2. Create a Route 53 Profile in the shared services account.
  3. Associate the interface VPC endpoint for OpenSearch Serverless with the Route 53 Profile.
    1. The Route 53 Profile automatically associates the hidden private hosted zone with the profile.
  4. Associate the private hosted zone us-east-1.aoss.amazonaws.com that was automatically created by OpenSearch Serverless with the Route 53 Profile.
  5. Share the Route 53 Profile with your other AWS accounts in your organization using AWS Resource Access Manager (AWS RAM).
  6. Associate the spoke VPCs (located in different accounts) with the Route 53 Profile.

If you have an existing Route 53 Profile in your shared services account that is already associated to spoke VPCs, you can simply associate the OpenSearch Serverless interface VPC endpoint and the private hosted zone us-east-1.aoss.amazonaws.com to this profile.

After completing these steps, the DNS resolution for the OpenSearch Serverless collection and dashboard endpoints works seamlessly from spoke VPCs associated with the Route 53 Profile. Clients in spoke VPCs can resolve and access OpenSearch Serverless collections and dashboards through the centralized VPC endpoint.

Pattern 2: Distributed interface VPC endpoint for OpenSearch Serverless

Each spoke VPC, residing in its respective AWS account, hosts its own OpenSearch Serverless collection and interface VPC endpoint. We now want to achieve the following:

  • Centralize DNS management in a shared services VPC to provide consistent resolution for OpenSearch Serverless collections deployed across multiple spoke accounts
  • Provide on-premises resources with DNS resolution capability for all OpenSearch Serverless collections across the organization through a Route 53 Resolver inbound endpoint in the shared services VPC

The following diagram illustrates this architecture.

AOSS Distributed

Challenge

Managing DNS resolution for OpenSearch Serverless collections and dashboards becomes complex in this distributed model because each interface VPC endpoint creates its own set of private hosted zones that are only associated with their respective VPCs. This creates a fragmented DNS landscape where the shared services VPC and on-premises networks need a consolidated way to resolve domains of OpenSearch Serverless collections and dashboards across multiple spoke accounts.

Solution: Use a self-managed private hosted zone in the shared services VPC for on-prem DNS resolution

To enable centralized DNS resolution for distributed endpoints, create a self-managed private hosted zone in the shared services account and associate it with the shared services VPC. Within this private hosted zone, you can create CNAME records that map each OpenSearch Serverless collection endpoint to its respective interface VPC endpoint DNS names in the spoke accounts. The following diagram illustrates this architecture.

AOSS Distributed Centralized DNS On Prem and VPC

Implementation consists of the following steps:

  1. Create a self-managed private hosted zone in the shared services account with the domain name us-east-1.aoss.amazonaws.com and associate it with the shared services VPC. For each OpenSearch Serverless collection, create a CNAME record that points to the Regional DNS name of its corresponding interface VPC endpoint.

This configuration enables both on-premises resources and resources in the shared services VPC to resolve OpenSearch Serverless endpoints that are in the spoke accounts.

After you complete these steps, each OpenSearch Serverless interface VPC endpoint remains within its original AWS account, maintaining security boundaries and account-level autonomy. On-premises systems can access OpenSearch Serverless collections and dashboards using original collection DNS names (for example, {collection-name}.us-east-1.aoss.amazonaws.com) through DNS resolution provided by the private hosted zone in the shared services VPC.

Conclusion

As organizations scale their adoption of OpenSearch Serverless, establishing secure and centralized network access becomes increasingly important. In this post, we explored two architectural patterns specifically around DNS management:

  • Centralized endpoint model – This pattern is ideal when a shared services account manages the OpenSearch Serverless interface VPC endpoints, allowing multiple spoke accounts to access OpenSearch Serverless collections and dashboards through a centralized set of network resources.
  • Distributed endpoint model with centralized DNS – This pattern is suitable for organizations that require account-level autonomy, where each AWS account manages its own OpenSearch Serverless interface VPC endpoints, while DNS resolution is centralized through a shared self-managed private hosted zone in a shared services account.

By understanding the DNS architecture of OpenSearch Serverless and using services like Route 53 Profiles and AWS RAM, organizations can build secure and robust access patterns that align with their organizational structure and needs.


About the Authors

Ankush GoyalAnkush Goyal is a Enterprise Support Lead in AWS Enterprise Support who helps customers streamline their cloud operations on AWS. He is a results-driven IT professional with over 20 years of experience.

Anvesh KogantiAnvesh Koganti is a Solutions Architect at AWS specializing in Networking. He focuses on helping customers build networking architectures for highly scalable and resilient AWS environments. Outside of work, Anvesh is passionate about consumer technology and enjoys listening to podcasts on tech and business. When disconnecting from the digital world, Anvesh spends time outdoors hiking and biking.

Salman AhmedSalman Ahmed is a Senior Technical Account Manager in AWS Enterprise Support. He specializes in guiding customers through the design, implementation, and support of AWS solutions. Combining his networking expertise with a drive to explore new technologies, he helps organizations successfully navigate their cloud journey. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Protect against advanced DNS threats with Amazon Route 53 Resolver DNS Firewall

Post Syndicated from Lawton Pittenger original https://aws.amazon.com/blogs/security/protect-against-advanced-dns-threats-with-amazon-route-53-resolver-dns-firewall/

Every day, millions of applications seamlessly connect users to the digital services they need through DNS queries. These queries act as an interface to the internet’s address book, translating familiar domain names like amazon.com into the IP addresses that computers use to appropriately route traffic. The DNS landscape presents unique security challenges and opportunities in Amazon Virtual Private Cloud (Amazon VPC) environments. First, DNS resolution acts as an early checkpoint that you can use to control network traffic before it even begins. Second, DNS queries in your VPC follow a distinct path through the Amazon Route 53 Resolver that operates independently from your standard internet gateway, bypassing other network security controls.

To address this, Amazon Route 53 Resolver DNS Firewall provides protection for DNS traffic, starting with traditional domain lists where you can explicitly allow or deny DNS resolution of specific domains. Also, included are AWS Managed Domain Lists, which automatically block known malicious domains identified through Amazon Threat Intelligence and our trusted security partners. While this approach works effectively to help prevent known threats, sophisticated bad actors are increasingly using techniques that traditional blocklists can’t catch.

Instead of relying solely on static lists, Amazon Route 53 Resolver DNS Firewall Advanced provides intelligent protection alongside these traditional controls. These advanced rules work like a skilled security analyst, watching for suspicious patterns in DNS queries in real time. By examining characteristics such as query length, entropy, and frequency, the service can spot potentially malicious activity even when encountering previously unknown domains. This approach enables detecting and blocking advanced threats like DNS tunneling and domain generation algorithms (DGAs)—techniques that bad actors use to establish hidden communication channels or connect malware to their control servers.

In this post, we take you on a practical journey exploring these DNS-based threats and tools to help prevent them. You’ll learn how to set up effective Route 53 Resolver DNS Firewall Advanced rules, and we provide a ready-to-deploy CloudFormation template with our recommended configurations. Finally, we demonstrate an example of real-world threat detection and show you how the service integrates with AWS Security Hub to improve visibility of alerts. By the time you finish reading this post, you’ll have a clear understanding of how to deploy Route 53 Resolver DNS Firewall rules to add an intelligent, proactive layer of security to your AWS environment.

Understanding the risks of DNS tunneling and DGAs

As mentioned earlier, the Route 53 Resolver provides a service-managed path to the internet that operates independently from your VPC’s internet gateway. While this architecture enables efficient DNS resolution, it can be exploited through techniques such as DNS tunneling. Let’s explore how these techniques work and why they present unique challenges.

DNS tunneling takes advantage of the DNS protocol’s basic function—asking questions about domain names and receiving answers from the authoritative nameserver for the domain. But instead of using DNS for its intended purpose of domain name resolution, tunneling encodes other types of data within DNS queries and responses. For example, rather than asking simply what is the IP address for example.com?, a tunneling exploit might embed data within a query like secretdata123.attacker.com, where secretdata123 contains encoded information. This can lead to DNS being used as a two-way communications command and control channel. Detecting and blocking DNS tunneling is a vital control for stopping data exfiltration and command and control (C2) communications.

DGAs represent a different challenge for DNS security. Rather than using a fixed, predictable domain name that can be quickly blocked, DGAs automatically create many possible domain names using mathematical formulas, which are then used as a destination for C2 traffic. For instance, a DGA might generate domains like xkt7py.com today and mn9qrs.com tomorrow. This makes it difficult to maintain effective blocklists, because the domains change frequently and appear random. Traditional threat intelligence feeds, which rely on identifying and blocking known malicious domains, struggle to keep pace with DGA-generated domains.

How DNS Firewall Advanced works

When examining a domain name, Route 53 Resolver DNS Firewall Advanced looks at multiple characteristics that help distinguish between legitimate and suspicious domains. For example, legitimate domain names typically use real words and follow predictable patterns that are designed to facilitate a human’s ability to recall and enter them accurately. In contrast, domains used for tunneling or generated by DGAs often contain random-looking strings of characters or unusual patterns.

Route 53 Resolver DNS Firewall Advanced builds its intelligence on extensive analysis of real-world domain usage patterns. It learns what legitimate domain names look like by studying the most resolved domains on the internet, combined with actual domain resolution patterns from across AWS. This real-world training data helps establish a baseline for normal domain name characteristics. DNS Firewall Advanced then contrasts these patterns against known techniques used in DNS tunneling and domain generation to identify suspicious activity.

The service analyzes various aspects of each domain name, including:

  • How the domain name is structured and broken into parts
  • The patterns of letters and numbers used
  • How closely the domain resembles natural language
  • The presence of common words versus random character combinations

The service analyzes queries in real time, processing each one in less than a millisecond, which maintains strong security controls without affecting your applications’ performance.

Route 53 Resolver DNS Firewall Advanced has customized protection levels that you can use to choose how aggressively you want to detect and respond to suspicious domains through confidence thresholds:

  • High confidence: This setting focuses on the most obvious threats, minimizing false positives. It’s ideal for production environments where blocking legitimate traffic could be disruptive.
  • Medium confidence: Provides balanced protection, suitable for most environments.
  • Low confidence: Offers the most detection but might require more tuning to avoid false positives. This setting is useful for high-security environments or for initial monitoring to understand traffic patterns.

You can combine these confidence levels with different actions (block or alert) to create a defense strategy that matches your security needs.

Manually create a DNS Firewall Advanced rule:

To start, we show you how to manually create a Route 53 Resolver DNS Firewall Advanced rule in the AWS Management Console. This rule will block DNS queries that it has detected to be DNS tunneling with high confidence.

To manually create a rule:

  1. In the Route 53 console, choose Rules in the navigation pane, and then choose Add rule.
    Figure 1: Rules in the Route 53 console

    Figure 1: Rules in the Route 53 console

  2. Enter a name for the rule and select DNS Firewall Advanced protections.
    Figure 2: Add a rule

    Figure 2: Add a rule

  3. Under DNS Firewall Advanced protection:
    1. Select DNS tunneling detection.
    2. For Confidence threshold, select High.
    3. Leave the Query type empty so that the rule applies to all query types.
    Figure 3: Select DNS protection options

    Figure 3: Select DNS protection options

  4. Under Action:
    1. Select Block.
    2. For the response, select OVERRIDE.
    3. For the Record value, enter dns-firewall-advanced-block.
    4. For the Record type, select CNAME.
    5. Choose Add rule.
    Figure 4: Configure actions for the rule

    Figure 4: Configure actions for the rule

We’ve created an AWS CloudFormation stack that deploys the following recommended Route 53 Resolver DNS Firewall rules in a DNS Firewall rule group. We recommend this configuration because it provides a balanced security approach—blocking high-confidence threats immediately while generating alerts for lower-confidence detections.

The inclusion of the AWS Managed Aggregate Threat List is particularly valuable because it combines domains from multiple threat categories (malware, ransomware, botnet, spyware, and DNS tunneling) into a blocklist. This consolidated list includes the domains from other AWS Managed Domain Lists, including those identified by GuardDuty threat intelligence systems, giving you broad protection against known malicious domains while the Route 53 DNS Firewall Advanced rules catch previously unseen threats.

For enterprise environments, you can scale this protection across your entire organization by using AWS Firewall Manager to automatically deploy and manage this rule group configuration consistently across the VPCs in your organization.

  • BLOCK – Aggregate Threat List (domains associated with multiple DNS threat categories including malware, ransomware, botnet, spyware, and DNS tunneling to help block multiple types of threats)
  • BLOCK – DNS Tunneling | Confidence: HIGH
  • BLOCK – DGAs | Confidence: HIGH
  • ALERT – DNS Tunneling | Confidence: LOW
  • ALERT – DGAs | Confidence: LOW

To deploy this rule group using a CloudFormation stack:

  1. Navigate to the CloudFormation console, choose Stacks from the navigation pane. Choose Create Stack in the upper right and select With new resources (standard).
    Figure 5: Create a stack

    Figure 5: Create a stack

  2. Download the CloudFormation template. Select Choose an existing template and then select Upload a template file and upload the CloudFormation stack. Choose Next.
    Figure 6: Use the CloudFormation template

    Figure 6: Use the CloudFormation template

  3. Enter a stack name and choose Next.
    Figure 7: Enter a stack name

    Figure 7: Enter a stack name

  4. Leave the default values for all options, select Next, and then choose Submit.
  5. Navigate to the Route 53 Resolver DNS Firewall by visiting the Amazon VPC console, scroll down to the DNS firewall section, and select the Rule groups tab.
  6. Select the newly created rule group.
  7. Select the Associated VPCs tab, choose Associate VPC, and then associate a VPC you want to protect and choose Associate.
    Figure 8: Associate a VPC

    Figure 8: Associate a VPC

Observability

Route 53 Resolver query logging provides detailed visibility into DNS queries made from resources associated with your VPCs, enabling you to monitor and analyze your DNS traffic for security and compliance purposes. By configuring query logging, you can capture essential information about each DNS request, including the domain name being queried, the record type, the response code, and the originating VPC and instance. Query logging is particularly valuable when used in conjunction with Route 53 Resolver DNS Firewall, because it helps you track blocked queries and fine-tune your security rules based on actual DNS traffic patterns in your environment. The following are examples of log entries generated when DNS Firewall detects and responds to suspicious activities, showing the detailed information available for security analysis and incident response.

Example log entry: DNS tunneling block

The following is an example of a DNS tunneling block.

{
    "version": "1.100000",
    "account_id": "11111111111",
    "region": "us-west-2",
    "vpc_id": "vpc-0fcc85bd45b791d5a",
    "query_timestamp": "2025-02-05T03:54:12Z",
    "query_name": "1WTE4CyL4Vf1LQDDAToimuqFBEtMXyYMsYP8zPgVyTagzSh5PvinuQcL6N8at4A.REZv3VqKU4x43DPcCKAzQk4UKoZjB3nDMukHAuKTtDckTqZ8SDDZ1iXRey6a5sD.mEDMdrzPocS9exqoBQ1xfSuKfvW.1.dnstunnel.com.",
    "query_type": "A",
    "query_class": "IN",
    "rcode": "NXDOMAIN",
    "answers": [
        {
            "Rdata": "dns-firewall-advanced-block.",
            "Type": "CNAME",
            "Class": "IN"
        }
    ],
    "srcaddr": "10.1.0.122",
    "srcport": "41859",
    "transport": "UDP",
    "srcids": {
        "instance": "i-0c738190f19db9a2c"
    },
    "firewall_rule_action": "BLOCK",
    "firewall_rule_group_id": "rslvr-frg-63efa138b43f428b",
    "firewall_protection": "DNS_TUNNELING"
}

Example log entry: DNS tunneling alert

The following is an example of a DNS tunneling alert.

{
    "version": "1.100000",
    "account_id": "11111111111",
    "region": "us-west-2",
    "vpc_id": "vpc-0fcc85bd45b791d5a",
    "query_timestamp": "2025-02-05T04:00:02Z",
    "query_name": "1WTEc8GwFH3qHY8XKjbhXuj43yGShMrhacqwJYSZkSqRQ95sagz64NUpnuj4R8R.S79aru2KRB8d9nCHEPdXWJxGT4aUjVMqtCRSq9EZXRCo8NH5cmLvmcho3hh1mbK.NqGY1X6M4qpMGX6dnTSHuCsZFbf.1.dnstunnel.com.",
    "query_type": "A",
    "query_class": "IN",
    "rcode": "NOERROR",
    "answers": [
        {
        "Rdata": "202.92.34.217",
        "Type": "A",
        "Class": "IN"
        }
    ],
    "srcaddr": "10.1.0.122",
    "srcport": "35116",
    "transport": "UDP",
    "srcids": {
        "instance": "i-0c738190f19db9a2c",
        "resolver_endpoint": "rslvr-out-e20639d3666748f58"
    },
    "firewall_rule_action": "ALERT",
    "firewall_rule_group_id": "rslvr-frg-63efa138b43f428b",
    "firewall_protection": "DNS_TUNNELING"
}

Integration with Security Hub

Security Hub provides you with a view of your security state in AWS and helps you to check your environment against security industry standards and best practices. Security Hub collects security data from across AWS accounts, AWS services, and supported third-party partner products, and helps you to analyze security trends and identify the highest priority security issues. It enables findings from both the Amazon: Route 53 Resolver DNS Firewall – AWS List and Amazon: Route 53 Resolver DNS Firewall Advanced list by default, so you’ll automatically receive these alerts without additional configuration. You only need to manually enable Amazon: Route 53 Resolver DNS Firewall – Custom List findings if you’re using custom domain lists in your rule groups. See Sending findings from Route 53 Resolver DNS Firewall to Security Hub for more information.

The following figure is an example of how Route 53 Resolver DNS Firewall Advanced findings appear in the Security Hub console, providing you with actionable security intelligence directly in your centralized dashboard.

Figure 9: DNS Firewall Advanced findings in Security Hub

Figure 9: DNS Firewall Advanced findings in Security Hub

Select a finding to view details such as Finding ID, Types, Workflow status, and so on.

Figure 10: Findings details

Figure 10: Findings details

Conclusion

Amazon Route 53 Resolver DNS Firewall Advanced represents a significant step forward in protecting organizations against sophisticated DNS-based threats. As mentioned, DNS queries sent to the Route 53 Resolver follow a unique path that bypasses traditional AWS security controls like security groups, NACLs, and even AWS Network Firewall—creating a security gap in many environments. Throughout this post, we’ve explored how DNS tunneling and DGA-based exploits take advantage of this blind spot, and how you can use Route 53 Resolver DNS Firewall Advanced to protect from these threats through real-time pattern analysis and anomaly detection. You learned how to configure the service in the AWS console and use the provided CloudFormation template with recommended rules that balance blocking high-confidence threats while alerting on potential issues. And you saw how query logging provides valuable visibility into your DNS traffic and how Security Hub integration centralizes your security findings. Implementing these capabilities helps you protect your infrastructure from sophisticated DNS-based exploits that traditional domain blocklists cannot catch, strengthening your cloud security posture while maintaining operational efficiency.

If you have feedback about this post, submit comments in the Comments section below.

Lawton Pittenger

Lawton Pittenger

Lawton is a Security Solutions Architect at AWS, based in New York City, focused on helping customers implement native AWS security services. Professionally, Lawton has worked in IT security roles, securing cloud environments. Outside of cloud security, his interests include skateboarding, snowboarding, and rock climbing.

Michael Leighty

Michael Leighty

Michael is a Senior Security Solutions Architect at AWS, based in Atlanta. He specializes in helping customers design and implement effective network security controls, drawing from extensive experience at leading network security vendors. At AWS, he works closely with service teams to drive continuous improvement in security services based on customer needs and feedback.

How UNiDAYS achieved AWS Region expansion in 3 weeks

Post Syndicated from Sanhawat Taongern original https://aws.amazon.com/blogs/architecture/how-unidays-achieved-aws-region-expansion-in-3-weeks/

UNiDAYS is a fast, free digital platform that provides exclusive student offers and benefits to over 29 million verified members worldwide. With a rapidly growing user base and an increasing number of global partnerships, UNiDAYS recognized the need to enhance its platform’s performance to deliver a seamless consumer experience in geographic regions far from its original base of operations.

In this post, we share how UNiDAYS achieved AWS Region expansion in just 3 weeks using AWS services.

Business challenges

In response to growth opportunities, UNiDAYS faced a pressing business requirement: deliver low-latency responses and provide high availability for users across diverse geographic regions. At the same time, the platform needed to guarantee global data consistency while adhering to tight deadlines—all within just a few weeks. However, the existing monolithic application, although built on Amazon Web Services (AWS), wasn’t optimized for active-active multi-Region deployments.

The challenge was further complicated by the need to extend functionality from this legacy system, which used the AWS global network for improved user experience but fell short of meeting new business requirements. Re-architecting the entire platform to support multi-Region deployments within the given timeframe wasn’t feasible.

Solution overview

UNiDAYS opted to create complementary services tailored to these new requirements, using AWS services for a multi-Region, active-active architecture. The key services used included:

This approach allowed UNiDAYS to meet its latency, availability, and consistency goals while seamlessly integrating with existing infrastructure. The following diagram is the architecture for the solution.

Global delivery and resiliency

To provide the lowest latency and multi-Region resiliency, CloudFront was used with latency-based routing configured in Route 53. This routing directs requests to the Regional Application Load Balancers with the lowest latency, automatically providing resiliency in the event of Regional issues. Security was a key consideration. AWS WAF integration with CloudFront provided application-layer protection at the edge. Additional security measures included:

  • Custom HTTP headers on origin requests, enforced using Application Load Balancer listener rule conditions
  • Prefix lists to restrict access to Application Load Balancers, making sure that traffic originated from the intended CloudFront distributions

Rapid Regional deployment

The core infrastructure is deployed through Terraform, and applications are deployed using custom tooling that wraps AWS CloudFormation. This hybrid approach enabled rapid delivery by using existing patterns without disrupting established workflows. Resources were organized into tiers: platform, global, and Regional. Platform and global resources were deployed one time, and Regional resources were rolled out to each activated Region, streamlining expansion efforts.

One technical challenge involved CloudFormation exports, which are Regional by design. To address this, we implemented a custom CloudFormation macro to enable cross-Region access to exported values, providing consistency across deployments.

Amazon ECS enabled progressive application deployments within each Region, allowing teams to focus on scaling applications rather than managing infrastructure. For cost-efficiency, we used Spot Instances. During testing, container start-up latency was observed due to cross-Region image downloads from Amazon Elastic Container Registry (Amazon ECR). This issue was resolved by enabling private image replication in Amazon ECR so that container images were available locally in each Region. This solution significantly reduced start-up times, improving application responsiveness during deployments and scaling events.

Data consistency and performance

DynamoDB global tables were instrumental in providing eventual data consistency and Regional replication. With DynamoDB handling these aspects, we could focus on application logic.

The result was a substantial reduction in latency at key locations. For example, client-experienced latency in one Region dropped from approximately 200 milliseconds to 50 milliseconds upon deployment, as shown in the following screenshot.

Outcome

Key technical hurdles

We addressed the following technical obstacles while developing the solution:

  • Cross-Region CloudFormation exports – CloudFormation exports are Regional by design. We addressed this by creating a custom CloudFormation macro to read exports across Regions.
  • Container start-up latency – Latency caused by cross-Region image downloads was mitigated by implementing Amazon ECR private image replication. This meant that container images were readily available in each Region, reducing deployment times and improving overall performance.
  • Security assurance – By using CloudFront, AWS WAF, and Application Load Balancer security features, we made sure that traffic and data remained secure.

Why AWS?

UNiDAYS chose AWS due to its comprehensive global infrastructure and robust service offerings, which allowed the platform to:

  • Seamlessly expand compute operations to Regions closer to its user base
  • Take advantage of a full stack of services for reliable, secure, and low-latency content delivery
  • Meet tight delivery deadlines without compromising on performance or security
  • Maintain flexibility where required, with the ability to use more managed services, which allowed a focus on our applications

Conclusion

By adopting a multi-Region, active-active architecture on AWS, UNiDAYS successfully met its business goals within only 3 weeks, rapidly expanding to new Regions while promoting platform resiliency. The solution improved latency by 75% in new Regions (from 200 milliseconds to 50 milliseconds), provided Regional data availability through DynamoDB global tables, and maintained 100% service uptime during resiliency tests, even in cases of Regional connectivity loss. Additionally, deployment velocity increased by over 40%, allowing faster feature releases and improved agility. This architecture not only provides a scalable and resilient platform for current operations but also establishes a strong foundation for future global expansion.

Learn more

Is your organization looking to expand into new Regions while maintaining performance and reliability?

  • Contact AWS experts to explore tailored solutions for your multi-Region strategy.
  • Use AWS Global Infrastructure to optimize your expansion.
  • Share your challenges and successes in the comments—we’d love to hear your insights!


About the Authors

Amazon API Gateway now supports dual-stack (IPv4 and IPv6) endpoints

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/amazon-api-gateway-now-supports-dual-stack-ipv4-and-ipv6-endpoints/

Today, we are launching IPv6 support for Amazon API Gateway across all endpoint types, custom domains, and management APIs, in all commercial and AWS GovCloud (US) Regions. You can now configure REST, HTTP, and WebSocket APIs, and custom domains, to accept calls from IPv6 clients alongside the existing IPv4 support. You can also call API Gateway management APIs from dual-stack (IPv6 and IPv4) clients. As organizations globally confront growing IPv4 address scarcity and increasing costs, implementing IPv6 becomes critical for future-proofing network infrastructure. This dual-stack approach helps organizations maintain future network compatibility and expand global reach. To learn more about dualstack in the Amazon Web Services (AWS) environment, see the IPv6 on AWS documentation.

Creating new dual-stack resources

This post focuses on two ways to create an API or a domain name with a dualstack IP address type: AWS Management Console and AWS Cloud Development Kit (CDK).

AWS Console

When creating a new API or domain name in the console, select IPv4 only or dualstack (IPv4 and IPv6) for the IP address type.

As shown in the following image, you can select the dualstack option when creating a new REST API.
For custom domain names, you can similarly configure dualstack as shown in the next image.

If you need to revert to IPv4-only for any reason, you can modify the IP address type setting, with no need to redeploy your API for the update to take effect.

REST APIs of all endpoint types (EDGE, REGIONAL and PRIVATE) support dualstack. Private REST APIs only support dualstack configuration.

AWS CDK

With AWS CDK, start by configuring a dual-stack REST API and domain name.

const api = new apigateway.RestApi(this, "Api", {
  restApiName: "MyDualStackAPI",
  endpointConfiguration: {ipAddressType: "dualstack"}
});

const domain_name = new apigateway.DomainName(this, "DomainName", {
  regionalCertificateArn: 'arn:aws:acm:us-east-1:111122223333:certificate/a1b2c3d4-5678-90ab',
  domainName: 'dualstack.example.com',
  endpointConfiguration: {
    types: ['Regional'],
    ipAddressType: 'dualstack'
  },
  securityPolicy: 'TLS_1_2'
});

const basepathmapping = new apigateway.BasePathMapping(this, "BasePathMapping", {
  domainName: domain_name,
  restApi: api
});

IPv6 Source IP and authorization

When your API begins receiving IPv6 traffic, client source IPs will be in IPv6 format. If you use resource policies, Lambda authorizers, or AWS Identity and Access Management (IAM) policies that reference source IP addresses, make sure they’re updated to accommodate IPv6 address formats.

For example, to permit traffic from a specific IPv6 range in a resource policy.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": "*",
      "Action": "execute-api:Invoke",
      "Resource": "execute-api:stage-name/*",
      "Condition": {
        "IpAddress": {
          "aws:SourceIp": [
            "192.0.2.0/24",
            "2001:db8:1234::/48"
          ]
        }
      }
    }
  ]
}

Summary

API Gateway dual-stack support helps manage IPv4 address scarcity and costs, comply with government and industry mandates, and prepare for the future of networking. The dualstack implementation provides a smooth transition path by supporting both IPv4 and IPv6 clients simultaneously.

To get started with API Gateway dual-stack support, visit the Amazon API Gateway documentation. You can configure dualstack for new APIs or update existing APIs with minimal configuration changes.

Betty

Special thanks to Ellie Frank (elliesf), Anjali Gola (anjaligl), and Pranika Kakkar (pranika) for providing resources, answering questions, and offering valuable feedback during the writing process. This blog post was made possible through the collaborative support of the service and product management teams.


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

From virtual machine to Kubernetes to serverless: How dacadoo saved 78% on cloud costs and automated operations

Post Syndicated from Andreas Gehrig original https://aws.amazon.com/blogs/architecture/from-virtual-machine-to-kubernetes-to-serverless-how-dacadoo-saved-78-on-cloud-costs-and-automated-operations/

dacadoo is a global Swiss-based technology company that develops solutions for digital health engagement and health risk quantification. Their products include a software-as-a-service (SaaS)-based digital health engagement platform that uses behavioral science, AI, and gamification to help end users improve their health outcomes.

The company embarked on a journey to modernize an API to quantify health and lifestyle data plus a risk engine to calculate mortality and morbidity probabilities based on years of scientific research data.

To transform a virtual machine–based API service into a globally redundant, scalable health score and risk calculation solution dacadoo chose Amazon Web Services (AWS) technology. The service handles highly sensitive health data from a global customer base and must comply with regional regulations.

The result is a cost reduction of 78% and an infrastructure maintenance effort of less than an hour per year , allowing dacadoo to deliver and operate more AWS infrastructure without scaling its site reliability engineering (SRE) team, thanks to a high level of automation and an agile mindset.

In this post, we walk you step-by-step through dacadoo’s journey of embracing managed services, highlighting their architectural decisions as we go.

Background

The solution architecture went through a three-stage journey:

  1. Incubation – Single virtual machine on premises with disaster recovery (DR) in Switzerland
  2. Global and scalable – Multiple global Kubernetes clusters
  3. Operational excellence – Fully serverless and geo-redundant on AWS

Stage 1: Incubation with a virtual machine

After years of scientific research and development, the service was launched, running on a single on-premises virtual machine that used hypervisor technology to provide disaster recovery (DR). However, it had no high availability (HA) capability and it required manual recovery.

The application serving the API requests and the NoSQL database were both running on the same host. Software deployment and operating system maintenance were performed manually using Secure Shell (SSH)—a typical low-automation setup that also included downtime.

The following architecture diagram shows a virtual machine encompassing the monolithic application and its database.

Monolithic architecture

Challenges

A single virtual machine was quick to set up and inexpensive to operate, but it had considerable shortcomings. The health API was only available in Switzerland, infrastructure maintenance was performed manually, and software deployment was handled manually. Additionally, database backups were done using virtual machine snapshots, uptime monitoring only, and testing was conducted on the developer workstation.

Stage 2: Global and scalable with Kubernetes

At that time, dacadoo made a strategic decision to heavily invest in Kubernetes for managing containerized workloads on a global scale. As part of this technology rollout, the health score and risk service were migrated to Kubernetes.

Due to the geographically distributed customer base and low latency requirements, three Kubernetes clusters were deployed, one on each continent. The NoSQL database was hosted in proximity to the workload to reduce service latency and keep the migration effort low.

To reduce the operational maintenance, the NoSQL database was integrated as a SaaS offering, and monitoring was centralized using Datadog.

All cloud infrastructure was provisioned exclusively with Terraform, covering the Kubernetes cluster, NoSQL database , and integration with GitLab and Datadog.

dacadoo containerized the API service and used Gitlab continuous integration and continuous deployment (CI/CD) pipelines to deploy multiple environments and clusters on a global hyperscaler.

In retrospect, this was a typical replatform modernization project from virtual machine to Kubernetes, with a high level of automation and a SaaS-first approach.

The following diagram is the architecture for the container solution with managed NoSQL database.

Containers architecture

Challenges

The service faced several challenges, including increased costs from deploying three regional Kubernetes clusters across three environments, resulting in 27 cluster nodes and additional expenses from managing NoSQL database SaaS instances for each cluster. The complexity of CI/CD pipelines for multi-environment multi-cluster deployments added to the difficulty. Significant operational effort was required to keep infrastructure and Kubernetes components up to date.

Stage 3: Operational excellence with serverless

The Kubernetes-based architecture met the requirements, but some features in the dacadoo API service backlog needed to fit better with the application architecture at the time.

This was the right moment to take a holistic view of the infrastructure and software architecture and refactor the solution according to the latest AWS technologies and best practices, the next frontier for dacadoo’s engineering team.

Solution requirements

Requirements for the solution refactoring were as follows:

  • Keep the functionality of the API unmodified
  • Constrain data processing to a region of choice for compliance with local data protection laws
  • Avoid weekly patch cycles by exclusively using managed serverless services
  • Reduce costs by choosing services with a pay-as-you-go billing model
  • Delegate authentication to a dedicated service
  • Use an established web framework with an extensive ecosystem

Refactoring the apps

The API service has two components: a developer portal and the health score and risk calculations API. The database is only required for API keys, algorithm parameters, quotas, and usage statistics. Health data is processed regionally by the compute layer but not persisted, opening the door for a distributed database: Amazon DynamoDB global tables is the perfect fit for the solution. Writes are distributed to all connected Regions, whereas reads are local, providing low latency for complying with dacadoo service level agreements (SLAs).

The developer portal is a web UI with API documentation and API key management features. AWS Lambda is a great fit because it scales automatically and has a pay-per-request billing model.

The health and risk API uses algorithms implemented in the C programming language for short bursting, compute-intense simulations. These calls are wrapped by a REST API using the Python FastAPI framework. These characteristics make AWS Lambda a great fit.

Serverless architecture

HTTP requests are routed to the Lambda functions using Amazon API Gateway with AWS WAF for protection from malicious requests and attacks. Static assets are served from an Amazon Simple Storage Service (Amazon S3) bucket through API Gateway. The additional features of Amazon CloudFront aren’t required, and Amazon S3 reduces the complexity.

Amazon Route 53 provides a powerful feature known as latency-based routing, which allows it to direct DNS queries to the endpoint that offers the lowest latency for the requester.

This feature provides Regional high availability for API users without data processing location requirements. Alternatively, the user can call specific Regional endpoints to make sure requests are processed in the desired Region.

API authorization is HTTP header-based and is performed in the application with data stored in Amazon DynamoDB.

The following diagram is the architecture for a geo-redundant fully serverless solution.

Serverless architecture

With a dacadoo SRE team proficient in Python, they opted for Pulumi for its advanced features such as programming language flow control constructs, powerful configuration capabilities, and multi-cloud support.

For continuous integration, GitLab CI compiles the algorithm library, tests the FastAPI applications and packages everything. The application deployment is just an update of the AWS Lambda, a simple and reliable workflow.

Summary

The solution evolved from a managed infrastructure setup, where the customer held most of the responsibility, to an AWS managed service architecture.

Infrastructure provisioning evolved from manual, error-prone processes to powerful code-driven workflows in Pulumi. The SRE needed to enhance their software engineering skills to adopt Pulumi, transitioning from configuration-based approaches to designing and maintaining an infrastructure code base using object-oriented Python. This was part of dacadoo’s investment in the SRE team and broader modernization efforts. The serverless architecture enabled a GitOps engineering culture focused on productivity.

The transformation maximized scalability and availability while reducing costs and operational effort:

Virtual machine

  • Scalability: Low
  • Availability: Best effort
  • Infrastructure costs: Low
  • Maintenance effort: High

Kubernetes

  • Scalability: High
  • Availability: 99.95%
  • Infrastructure costs: High
  • Maintenance effort: Medium

Serverless

  • Scalability: Very high
  • Availability: 99.999% (with failover to another AWS Region)
  • Infrastructure costs: Low
  • Maintenance effort: Very low

The global redundancy elevates availability to an impressive 99.999% while keeping the costs low.

Conclusion

Migrating from a virtual machine to Kubernetes and ultimately to AWS Lambda demonstrates the progression of cloud engineering toward enhanced efficiency and scalability.

Each step in this journey reduced the complexity of managing resources while increasing flexibility and automation. Transitioning dacadoo’s API service to a fully serverless, geo-redundant architecture not only advanced the platform but also upskilled engineers, maintained a lean SRE team, and kept infrastructure costs low. Get started with your own AWS serverless solution.


About the Authors

Top Architecture Blog Posts of 2024

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

(By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

Without further ado, here are our top posts from 2024!

#10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

Architecture for deploying stable diffusion on ComfyUI

Figure 1. Architecture for deploying stable diffusion on ComfyUI

#9 Let’s Architect! Designing Well-Architected systems

In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

Let's Architect

Figure 2. Let’s Architect

#8 Let’s Architect! Learn About Machine Learning on AWS

As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

Let's Architect

Figure 3. Let’s Architect

If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

#7 Creating an organizational multi-Region failover strategy

Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

#6 Building a three-tier architecture on a budget

Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

Example of a three-tier architecture on AWS

Figure 5. Example of a three-tier architecture on AWS

#5 Announcing updates to the AWS Well-Architected Framework guidance

As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

Well-Architected logo

Figure 6. Well-Architected logo

#4 Let’s Architect! Serverless developer experience in AWS

One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

Let's Architect

Figure 7. Let’s Architect

#3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

Chaos engineering pattern for hybrid architecture (3-tier application)

Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

#2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

Well-Architected logo

Figure 9. Well-Architected logo

#1 How an insurance company implements disaster recovery of 3-tier applications

And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Thank you!

As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

For other top post lists, see our Top 10 and Top 5 posts from previous years.

How an insurance company implements disaster recovery of 3-tier applications

Post Syndicated from Amit Narang original https://aws.amazon.com/blogs/architecture/how-an-insurance-company-implements-disaster-recovery-of-3-tier-applications/

A good strategy for resilience will include operating with high availability and planning for business continuity. It also accounts for the incidence of natural disasters, such as earthquakes or floods and technical failures, such as power failure or network connectivity. AWS recommends a multi-AZ strategy for high availability and a multi-Region strategy for disaster recovery. In this post, we explore how one of our customers, a US-based insurance company, uses cloud-native services to implement the disaster recovery of 3-tier applications.

At this insurance company, a relevant number of critical applications are 3-tier Java or .Net applications. These applications require access to IBM DB2, Oracle, or Microsoft SQLServer databases that run on Amazon EC2 instances. The requirement was to create a disaster recovery strategy that implements a Pilot Light or Warm/Standby scenario. This design needs to keep costs at a minimum, and it needs to allow for failure detection and manual failover of resources. Furthermore, it needs to keep the Recovery Time Objective (RTO) and the Recovery Point Objective (RPO) under 15 minutes. Finally, the solution could not use any public resources.

The solution

Amazon Route53 Application Recovery Controller (Route53 ARC) helps manage and orchestrate application failover and recovery across multiple AWS Regions or on-premises environments. It is specifically focused on managing DNS routing and traffic management during failover and recovery operation; however, some customers decide to implement their own strategies for application recovery. In this blog, we are going to focus on how one of our financial services customer implements it.

The Well-Architected framework explains that a good disaster recovery plan needs to manage configuration drift. A good practice is to use the delivery pipeline to deploy to both Regions and to regularly test the recovery pattern. There are customers that go a step further and even choose to operate in the secondary Region for a period of time.

The solution chosen by one of our leading insurance customers encompasses two distinct scenarios: a failover and a failback scenario. The failover scenario covers a list of steps to failover applications from the primary Region to the secondary Region. The failback process is the return of the operations to the primary Region.

Failover

Our customer decided to test the Pilot Light scenario. This scenario considers an application and a database deployed both in the primary and secondary Regions. As a requirement to achieve the 15-minute RPO, an application deployed in the primary Region needs to replicate data to the secondary Region. This async replication is implemented for each of the company’s database engines (DB2, SQLServer, Oracle) using native tooling. Leveraging native tooling was an existing practice and going with it would help minimize any operational impact.

It is important to notice that the detection and failover mechanisms is created in the secondary Region. This ensures these components will remain available when the primary Region becomes unavailable. Another important aspect is to establish connectivity between the two networks. This is needed to allow for the database replication.

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 1. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

The failover procedure uses the following steps for detection and failover:

  1. An Amazon EventBridge scheduler runs the AWS Lambda function every 60 seconds.
  2. The Lambda function tests the application endpoint and adds a custom metric to Amazon CloudWatch. If the application is unavailable, a CloudWatch Alarm will start the Lambda Function that initiates the failover.
  3. A Lambda function initiates the failover by starting a Jenkins pipeline. The pipeline will failover the application and the database to the secondary Region. The Jenkins pipeline starts with a manual approval step, ensuring that the failover process does not start automatically.
  4. Once approvers validate the necessity of the failover, they approve the workflow, and the pipeline moves to the next stage.
  5. The pipeline failovers the database, promoting the database in the secondary Region to the primary state and enables write operations.
  6. Next, start or scale out application servers that run on EC2 instances or containers. This is important to assure they will support the increased load in the secondary Region once failover is complete.
  7. At this point, database and application servers are ready to receive load. Next, the Application Load Balancer (ALB) needs to failover to the secondary Region. Route53 failover routing policy automatically failovers between Regions, but this customer wanted to manually control this step using a health check. To implement a manual failover of the ALB, the pipeline creates a file in a designated S3 bucket. A Lambda function regularly checks if this file exists in the expected location. If so, it triggers a CloudWatch Alarm and the Route53 health check will fail. At this point, Route 53 will redirect traffic to the ALB in the secondary Region, becoming the new active endpoint.

Failback

The failback scenario starts when all the required services become online in the primary Region. AWS recommends using AWS Personal Health Dashboard to check for service health. Figure 2 illustrates the failback process in detail. It shows the step-by-step flow from initiating the failback procedure to the final DNS switchover, highlighting the key components and interactions involved in each stage. This visual representation helps to clarify the complex process of returning operations to the primary Region.

Diagram of the failback process

Figure 2. Diagram of the failback process

The failback procedure is implemented in six steps:

  1. A cloud operator or Site Reliability Engineer (SRE) initiates the failback procedure by submitting a form on an HTML page. A Lambda function starts a Jenkins pipeline.
  2. The pipeline initiates the delta sync replication of the database. This ensures that data changes made in the secondary Region are replicated to the primary Region.
  3. The next stage is a manual approval to recover back to the primary Region, where the SRE verifies that the databases are in sync and all services needed are online in the primary Region.
  4. Upon approval, the pipeline starts the application servers in the primary Region.
  5. Next, the database in the primary Region is promoted for write operations. The database endpoint in the secondary Region is updated to point to the primary Region’s database.
  6. As explained in the failover section, the DNS switchover depends on a file existing in S3. Since this file was created for our failover event, the pipeline will now remove this file. The Lambda function identifies the change and updates the state of the CloudWatch Alarm, then the Route53 Healthcheck will change the state. At this point, the ALB in the primary Region becomes active and failback completes successfully.

Benefits

This customer identified the following benefits in implementing this design:

  • Customizable solution that aligns with the company’s internal processes, operating model, and technologies in use
  • Standardized pattern applicable across the organization for applications with different technologies, including databases, Windows and Linux applications running on EC2
  • Recovery Point Objective (RPO) and Recovery Time Objective (RTO) of less than 15 minutes
  • A cost optimized solution that uses cloud native services to implement the detection and failover scenarios

Conclusion

The solution for the disaster recovery of 3-tier applications demonstrates this financial services customer’s commitment to ensuring business continuity and resilience. This design showcases the company’s ability to tailor their architecture to their specific requirements. Achieving an RPO and RTO of less than 15 minutes for critical applications is a remarkable feat. It ensures minimal disruption to business operations during regional outages.

Furthermore, this solution leverages existing technologies and processes within the company, allowing for seamless integration and adoption across the organization. The ability to standardize this pattern for applications with different technologies helps simplifying the operating model.

If you’re an enterprise seeking to enhance the resilience of your critical applications, this disaster recovery solution from one of our enterprise customers serves as an inspiring example. To further explore the disaster recovery strategies and best practices on AWS, we recommend the following resources: