Post Syndicated from Explosm.net original https://explosm.net/comics/bartender-2
New Cyanide and Happiness Comic
Post Syndicated from Explosm.net original https://explosm.net/comics/bartender-2
New Cyanide and Happiness Comic
Post Syndicated from Alex Boudreau original https://aws.amazon.com/blogs/architecture/how-clario-automates-phi-pii-detection-in-dicom-images-using-amazon-bedrock/
Clario, part of Thermo Fisher Scientific, uses Amazon Bedrock to automate PHI (Protected Health Information) and PII (Personally Identifiable Information) detection across thousands of DICOM (Digital Imaging and Communications in Medicine) image slices in clinical trials. Each image slice may carry PII or PHI hidden in metadata tags, in custom vendor fields, or burned directly into the pixels. Across imaging sites, central labs, sponsors, and CROs (Contract Research Organizations), every one of those slices must be cleared of PII and PHI before the image moves downstream.
DICOM is the universal standard for storing, transmitting, and managing medical imaging data across healthcare systems. In clinical trials, DICOM images play a critical role by providing objective, quantifiable evidence of a patient’s medical condition throughout the study lifecycle. From baseline imaging to follow-up scans, modalities such as MRI, CT, PET, and X-ray generate DICOM files. Radiologists, clinicians, and sponsors use these files to assess treatment efficacy, monitor disease progression, and support regulatory submissions. These images serve as a core component of the clinical evidence package, making their accurate management and standardized handling essential to trial integrity.
In this post, we share how the Clario team designed an automated PHI and PII detection solution on AWS for DICOM imaging data, the key design decisions behind the architecture, and the lessons the team learned along the way.
Clario science and endpoint solutions support the clinical trials industry through the systematic collection, management, and analysis of specific, predefined outcomes (endpoints) to evaluate a treatment’s safety and effectiveness. For more than 50 years, Clario endpoint solutions have been deployed more than 30,000 times, and since 2015, they have supported more than 700 FDA and EMA new drug approvals.
Clearing PII and PHI from every image slice in the clinical trial is only part of the problem. The imaging workflow around this clearing process must be just as rigorous. A well-structured imaging workflow supports every DICOM file captured across globally distributed trial sites. Files are ingested automatically, consistently standardized, and rigorously validated at every step of the journey. Enforcing standardized image acquisition protocols across sites and geographies alleviates inconsistencies. These inconsistencies could otherwise impact data quality or delay regulatory submissions. A centralized imaging infrastructure that maintains complete metadata traceability, including acquisition parameters, imaging equipment details, and timestamps, supports a fully auditable workflow aligned with GCP (Good Clinical Practice) requirements. This empowers sponsors and CROs to move faster with greater confidence and significantly reduces the risk of data queries or compliance gaps.
An equally important aspect of managing DICOM imaging data in clinical trials is embedding intelligent, automated PHI and PII protection directly into the data management process. DICOM files carry more than images. They include metadata and tags, which can contain sensitive information such as patient names, dates of birth, medical record numbers, and facility identifiers. This sensitive information must be carefully managed before sponsors, CROs, or third-party stakeholders receive the data. Proactively verifying that PII and PHI are accurately identified and de-identified at the source is a critical best practice that safeguards patient privacy in compliance with HIPAA, GDPR, and ICH E6 guidelines. Automated de-identification tools that adhere to DICOM Supplement 142 and NEMA (National Electrical Manufacturers Association) standards reinforce data security and regulatory trust. They also preserve the full clinical and scientific value of imaging data, so trial teams can support confident, high-quality regulatory submissions.
To address these challenges, the Clario team built a comprehensive PHI/PII detection solution on AWS using Amazon Bedrock (Anthropic’s Claude Sonnet 4.5 on Amazon Bedrock) that combines automation, accuracy, and security throughout the clinical trial imaging workflow.
When evaluating options for building the solution, the Clario team chose to standardize on Amazon Bedrock and Amazon Textract for several key reasons:
The solution is built entirely on AWS, designed to bring greater efficiency, accuracy, and security to the detection of PHI and PII embedded within DICOM files. Accessible through Amazon API Gateway with TLS encryption in transit, IAM-backed authorization, and rate limiting, the detection workflow is readily consumable by multiple downstream systems with minimal integration effort.
Clinical trial sites store their DICOM images in Amazon Simple Storage Service (Amazon S3). The detection workflow retrieves each file from that bucket and processes it through the detection pipeline, so every ingestion step is logged and auditable for clinical trial security and compliance reviews. The workflow scans both standard and custom private DICOM metadata tags for PHI and PII. This covers the vendor-specific and non-standard tags where sensitive information often hides. Supporting both DICOM (.dcm) and PDF file formats, the solution is well-positioned to address PHI detection needs across the most used file types in clinical trial workflows.
The Clario AI team made a few deliberate design decisions early on. They ran the backend on Amazon Elastic Kubernetes Service (Amazon EKS) because a single DICOM series can span thousands of slices, and the detection workload is long-running and memory-intensive. They chose Amazon Relational Database Service (Amazon RDS) for PostgreSQL to persist processing metadata because the audit trail needs relational queries and strong consistency for compliance reporting. And they put the service behind Amazon API Gateway so that authentication, API-key management, and rate limiting are handled at the edge, keeping the backend focused on detection.
The following diagram and steps show how a DICOM document moves from upload through detection to structured output:
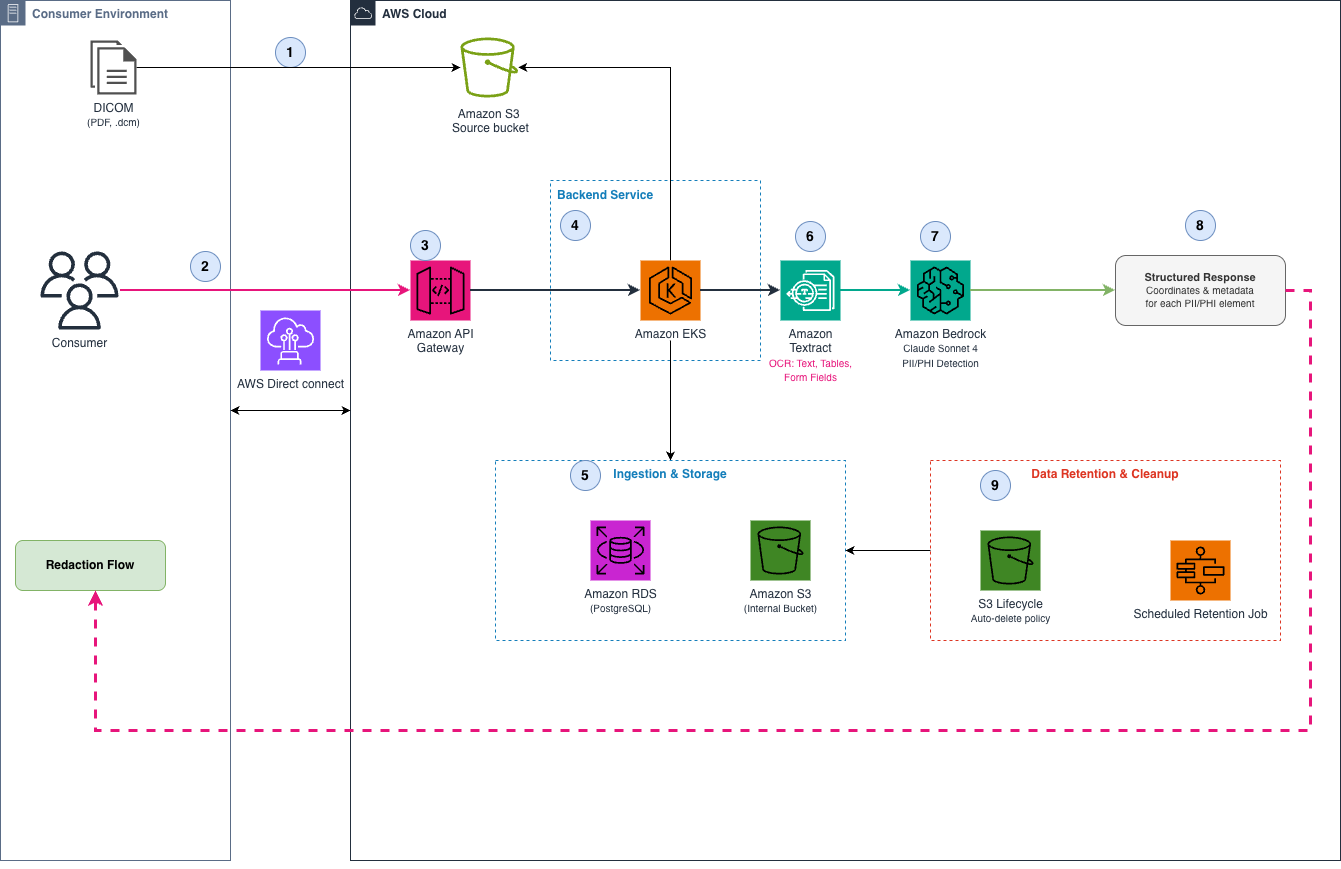
Figure 1: Solution architecture for DICOM image ingestion, detection pipeline, and data retention workflow
The following steps describe the data flow through the solution, as shown in the architecture diagram:
Beyond metadata, the solution uses Anthropic’s Claude Sonnet 4.5 on Amazon Bedrock to perform a deep scan of the actual image pixel content, detecting PHI or PII that may be physically burned into the image itself. This includes patient names, dates of birth, and patient IDs across every individual slice within a DICOM series that can span thousands of images.
When PHI or PII is identified, the solution precisely captures the spatial coordinates and type of sensitive information detected, passing these bounding box details downstream to integrated systems responsible for the actual pixel-level redaction. Separating detection from masking was a deliberate design decision. It preserves flexibility, supports full auditability, and a human-in-the-loop can review the flagged findings before redaction is applied.
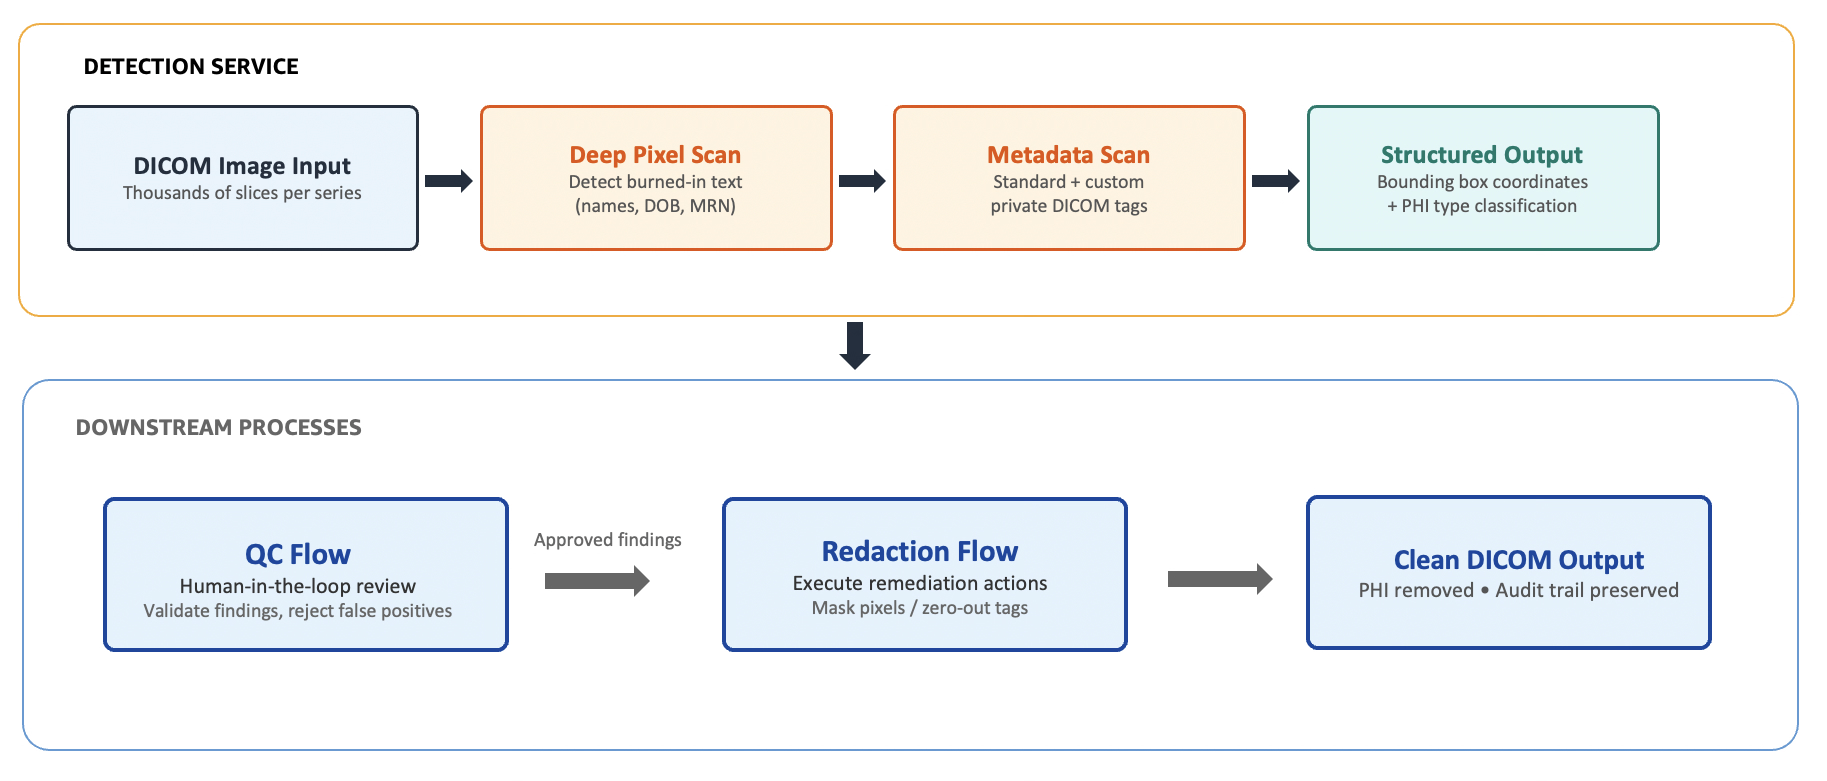
Figure 2: Deep image analysis and detection workflow showing the separation between AI-powered detection and human-supervised redaction
The detection solution returns structured coordinates for the identified PHI and PII, spanning burnt-in pixel text, standard DICOM header fields, and non-standard custom tags. The solution then hands these results off to two downstream processes. In the quality control (QC) flow, qualified reviewers validate the flagged findings and confirm which items require remediation. In the redaction flow, the system executes the appropriate action for each type of PHI identified: masking or overwriting burnt-in text within the image pixel data, or stripping and zeroing out sensitive DICOM metadata tags.
This separation of detection and redaction is intentional. The AI-powered detection solution focuses on comprehensive, high-recall identification across thousands of image slices and metadata fields. The redaction flow retains human oversight over the irreversible act of modifying clinical data, confirming that no PHI is left exposed and no clinically relevant information is removed.
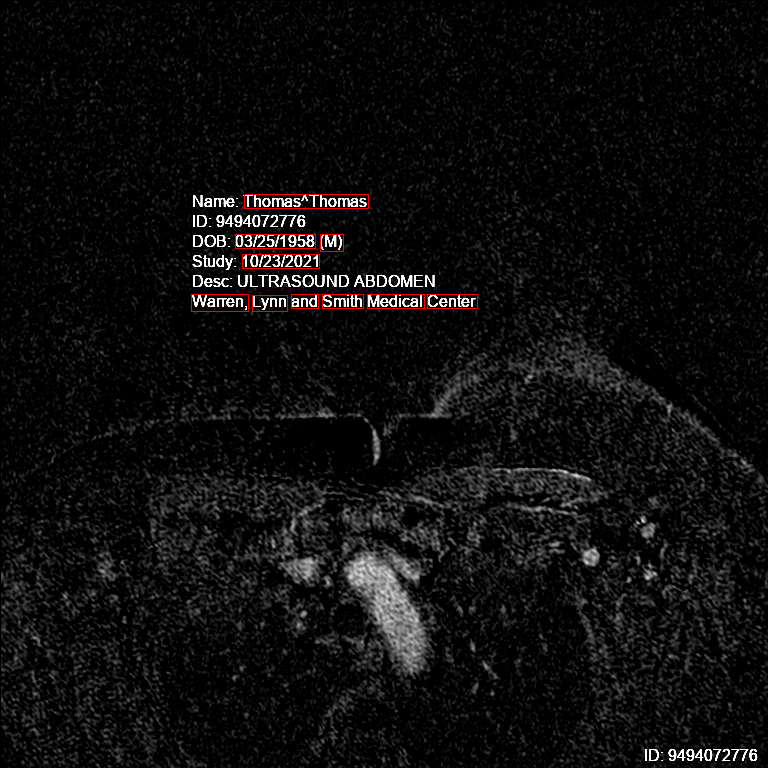
Figure 3: Sample DICOM image with detection
With the detection pipeline in place, the next step was to measure how accurately it identifies PHI and PII across real-world clinical documents.
The team validated the solution in three stages: building a representative test dataset, creating ground truth annotations, and running an automated evaluation pipeline.
The Clario generative AI team partnered with internal stakeholders to assemble a diverse dataset, including:
The dataset intentionally included documents that do and do not contain sensitive PII/PHI, allowing the team to measure both the model’s ability to detect sensitive information and its ability to avoid false alarms.
For each document in the dataset, ground truth labels were generated that capture:
These annotations form the “gold standard” that the Clario team can use to compare the output from the production pipeline.
The Clario team implemented a set of evaluation scripts that:
Furthermore, the solution includes automated accuracy and performance (run time) checks, to improve system reliability across deployments. After validating the solution’s accuracy, the team assessed how it improves detection coverage across Clario clinical trial imaging workflows.
The automated evaluation pipeline measured the solution’s detection performance against the manually annotated ground truth dataset across all three detection surfaces:
| Detection surface | Detection F1 | Label accuracy |
| PDF text | 0.9775 | 98.12% |
| DICOM burned-in image text | 0.9750 | 96.15% |
| DICOM metadata tags | 0.9951 | 99.60% |
Detection F1 measures how accurately the solution identifies PHI/PII instances. Label accuracy measures how correctly it classifies the type of identified PHI/PII (for example, person_name, date_of_birth, or gender).
These results demonstrate consistently high detection performance across all three data surfaces, with metadata tag detection achieving near-perfect accuracy. The solution meets the Clario generative AI team’s production-readiness bar for deployment in clinical trial workflows where compliance accuracy is non-negotiable.
Manual QC reviewers bring deep domain expertise to PHI identification. But modern clinical trials generate an enormous volume of data: thousands of image slices per series, each with dozens of metadata tags, including non-standard vendor-specific fields. This volume makes exhaustive manual review impractical at scale. The automated solution extends that human expertise across the full dataset.
In internal testing conducted by the Clario team, the solution scanned 100% of image slices, standard DICOM header fields, and custom private tags in the test dataset. This comprehensive coverage complements the existing QC process by surfacing PHI occurrences that might otherwise require additional review passes, particularly in non-standard private tags and burned-in pixel text where sensitive data is less predictable.
By automating PII and PHI detection across metadata tags and image slices, the solution can strengthen an organization’s compliance posture against HIPAA, GDPR, and ICH E6 requirements.
Beyond the measurable results, the project surfaced several insights that can guide other organizations building similar solutions.
The AWS Solutions Architecture team partnered with the Clario AI team throughout the design and optimization of the detection solution. Key areas of collaboration included:
Throughout the development and deployment of this solution, several valuable insights emerged that can benefit other organizations implementing similar AI-powered PHI detection systems for clinical trial imaging data.
The Clario AI team adopted a rigorous model evaluation process early in development. Many open-source frameworks and off-the-shelf detection models demonstrated acceptable performance on curated test samples but experienced significant accuracy degradation when exposed to the full variability of production data. This variability includes diverse imaging modalities, vendor-specific private tags, and inconsistent burned-in text formatting across globally distributed trial sites. This reinforced the importance of evaluating any AI model at realistic, production-level data volumes before adoption. The solution that proved most effective was a carefully tuned pipeline where Amazon Textract handles text extraction and Claude Sonnet on Amazon Bedrock performs PHI/PII classification, with prompt engineering optimized for the specific patterns found in clinical trial DICOM data.
Building a reliable, automated evaluation pipeline required the manual creation of a ground truth dataset. The team acknowledges this process is time-consuming but necessary. This highlighted a best practice that is frequently underestimated: investing in high-quality, manually validated ground truth data is a prerequisite for developing and maintaining a trustworthy automated detection system. Attempting to shortcut this step risks deploying a solution whose real-world accuracy remains unknown, an unacceptable risk in the context of clinical trial compliance.
The Clario team deliberately separated the PHI/PII detection function from the actual pixel-level redaction. Rather than performing masking directly, the solution identifies the precise coordinates and type of PHI/PII detected, passing this structured output downstream to integrated systems responsible for redaction. This separation proved to be a sound best practice. It preserves workflow flexibility, a human expert can review the findings before anyone makes irreversible changes to the image data, and keeps human accountability and auditability clear at every step.
Automation accelerates the detection and flagging process, but a key lesson learned is that human oversight should remain an integral part of the workflow. Incorporating a human review step for flagged findings before masking makes sure that edge cases and model uncertainties are appropriately handled. In the context of clinical trial data, where accuracy and regulatory accountability are paramount, this human-in-the-loop approach provides an essential layer of quality assurance that purely automated systems alone cannot fully replace.
The Clario automated PHI/PII detection solution demonstrates how AWS services can transform clinical trial imaging workflows by combining speed, accuracy, and compliance. By replacing manual spot-checks with automated scanning of every slice and metadata tag, the solution delivers complete PHI/PII detection coverage, reducing the risk of missed detections while strengthening compliance with HIPAA, GDPR, and ICH E6 requirements.
The key architectural decisions, comprehensive coverage of custom private tags, separation of detection from redaction, and human-in-the-loop validation provide a blueprint for other organizations managing sensitive imaging data in regulated environments. These lessons learned highlight that successful automation in clinical trials requires not just advanced technology, but thoughtful design that balances efficiency with the rigorous quality standards that patient safety and regulatory compliance demand.
Organizations looking to implement similar PHI/PII detection capabilities for clinical trial imaging can start by:
Post Syndicated from Kari Wilson original https://www.backblaze.com/blog/jamf-administrators-your-backup-deployment-just-got-simpler/
If you’re running a Mac fleet, Jamf is often where everything starts. It handles provisioning, policies, app installs——the orchestration that keeps your fleet sane. But backup is the thing that doesn’t fit. Jamf gives you control over every Mac, but it doesn’t protect the data on them. Backblaze closes that gap without changing how your team works.

Either you know who owns every device upfront (rare), or you don’t (common). Most teams end up doing some mix: devices that came pre-assigned, devices still waiting for user mapping, devices that migrated between teams. You write a script to fix it, then another to catch the next variation. Three months later, you’re not sure if every device is actually backed up or just supposed to be.
This update solves the core friction: you don’t have to choose one deployment model anymore.
Method 1: Fixed email (for controlled environments) If you already know who owns each device at install time, for example, if you have clean HR data synced to Jamf, you can pass the user email directly during deployment. The installer uses it to set up the account automatically. No guessing, no drift.
Method 2: Dynamic user detection (for real-world environments) If you don’t have clean data upfront (e.g. when new devices arrive, get imaged, and wait for assignment) the installer waits until a user logs in. Once a user signs in, Backblaze can automatically associate the device with the appropriate user account based on the deployment configuration and identity information available on the device. This reduces the need for manual user assignment and helps prevent devices from being left unprotected.
Or mix them: some devices get email, others get dynamic detection. The system can now handle both in the same deployment.
You push the Backblaze installer through a Jamf policy, same as any other app. Set your preferred method (fixed or dynamic) once at the group level, then let it run. Devices show up in the Backblaze console under the right user, with the right backup scope, no extra steps.
When something does need adjustment—a device moved teams, a user credential changed—you handle it the same way you’d handle any other Jamf-managed app. Script it, reconfigure it, whatever your existing process is. Backup can now follow the same deployment and management workflows your team already uses for other Jamf-managed applications.
The friction point used to be this: you’d deploy backup, then spend the next week chasing down why a handful of devices aren’t appearing correctly. Someone’s account didn’t match. A device landed in the wrong group. Now you’re writing workarounds.
With two deployment methods that actually handle different scenarios instead of forcing everything into one model. The new deployment options reduce common onboarding issues that often require follow-up troubleshooting. Fewer edge cases means fewer scripts to maintain, fewer devices to manually fix, fewer things to check on at 3am.
Nothing else about Backblaze changes. It backs up user data automatically, without caps or limits. Pricing stays flat per device. Restore works the same way. This update is purely about getting it deployed cleanly—the actual backup part just keeps working.
Pick a small group of devices. Deploy through Jamf. Watch what happens for a week. You’ll see pretty quickly whether the user-matching is working and whether this fits your environment.
How to install Backblaze silently with Jamf Pro for Mac
Learn more about Backblaze + Jamf
The post Jamf Administrators: Your Backup Deployment Just Got Simpler appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Post Syndicated from Sachin Jain original https://aws.amazon.com/blogs/architecture/ai-agents-for-clinical-trial-screening/
AI agents built on Amazon Bedrock AgentCore let clinical trial teams make fast, accurate enrollment decisions while keeping clinicians in control through human-in-the-loop oversight. According to the Tufts Center for the Study of Drug Development, 80 percent of clinical trials miss their enrollment timelines, and each day of delay costs an estimated $500,000.
Today, eligibility decisions rely on manual chart review across fragmented sources — EHR notes, lab results, imaging reports, and medication histories. Study teams spend hours reconstructing each candidate’s history and mapping it to protocol criteria. As protocols grow more complex, this doesn’t scale: screen failure rates stay high and enrollment targets slip.
We show how to architect a Clinical Trial Eligibility and Safety Agent on AWS that assembles patient evidence, evaluates it against protocol criteria, and presents screening recommendations with citations, while clinicians retain final authority and full audit trails. It combines AWS HealthLake for FHIR-native data access, Amazon Bedrock AgentCore for multi-step reasoning, and Amazon Bedrock AgentCore Evaluations for scoring each decision via LLM-as-a-judge and human-in-the-loop. This post is for solution architects, engineering teams, and technology leaders applying AI to clinical trial operations on AWS.
AI agents with Human-in-the-Loop (HIL) are well-suited for clinical trial eligibility and safety decisions because they address information fragmentation while preserving human clinical judgment. The core problem isn’t a lack of data, but that eligibility and safety signals are scattered across EHR notes, lab portals, imaging reports, and medication histories, forcing study teams to reconstruct each participant’s clinical picture. A knowledge graph addresses this by storing clinical data as entities and the relationships between them, representing each patient, molecule, endpoint, and market as a node with relationships stored as edges. To answer an eligibility or safety question, the agent traverses these edges, going from a diagnosis to its associated labs or a medication to its known interactions, rather than re-querying and joining disconnected sources each time. This structure supports the agent’s preparatory work:
Critically, the clinician remains the decision-maker. The agent organizes the supporting information. These systems augment rather than replace clinical reasoning — proposing preliminary assessments, flagging edge cases, providing confidence scores, and learning from feedback.
As protocols grow more complex with precision oncology and biomarker-driven eligibility, agents manage multi-step logic and maintain consistency across sites, while deferring final judgment to clinical staff.
This proposed architecture illustrates how core AWS services can be combined to create an end-to-end clinical trial screening pipeline. AWS HealthLake serves as the FHIR-native clinical data foundation, ingesting and normalizing patient records from disparate EHR systems, lab portals, and imaging archives into a unified, queryable data store. Amazon Bedrock AgentCore orchestrates the multi-step workflow assembling patient profiles, matching them against trial protocols, detecting safety signals, and generating evidence-backed screening recommendations. An Amazon Bedrock Knowledge Bases stores trial protocols, inclusion/exclusion criteria, and safety guidelines. The entire pipeline feeds into a clinician review dashboard where investigators examine agent reasoning, verify citations, and render final decisions. Actions are captured in an immutable audit trail for regulatory compliance.
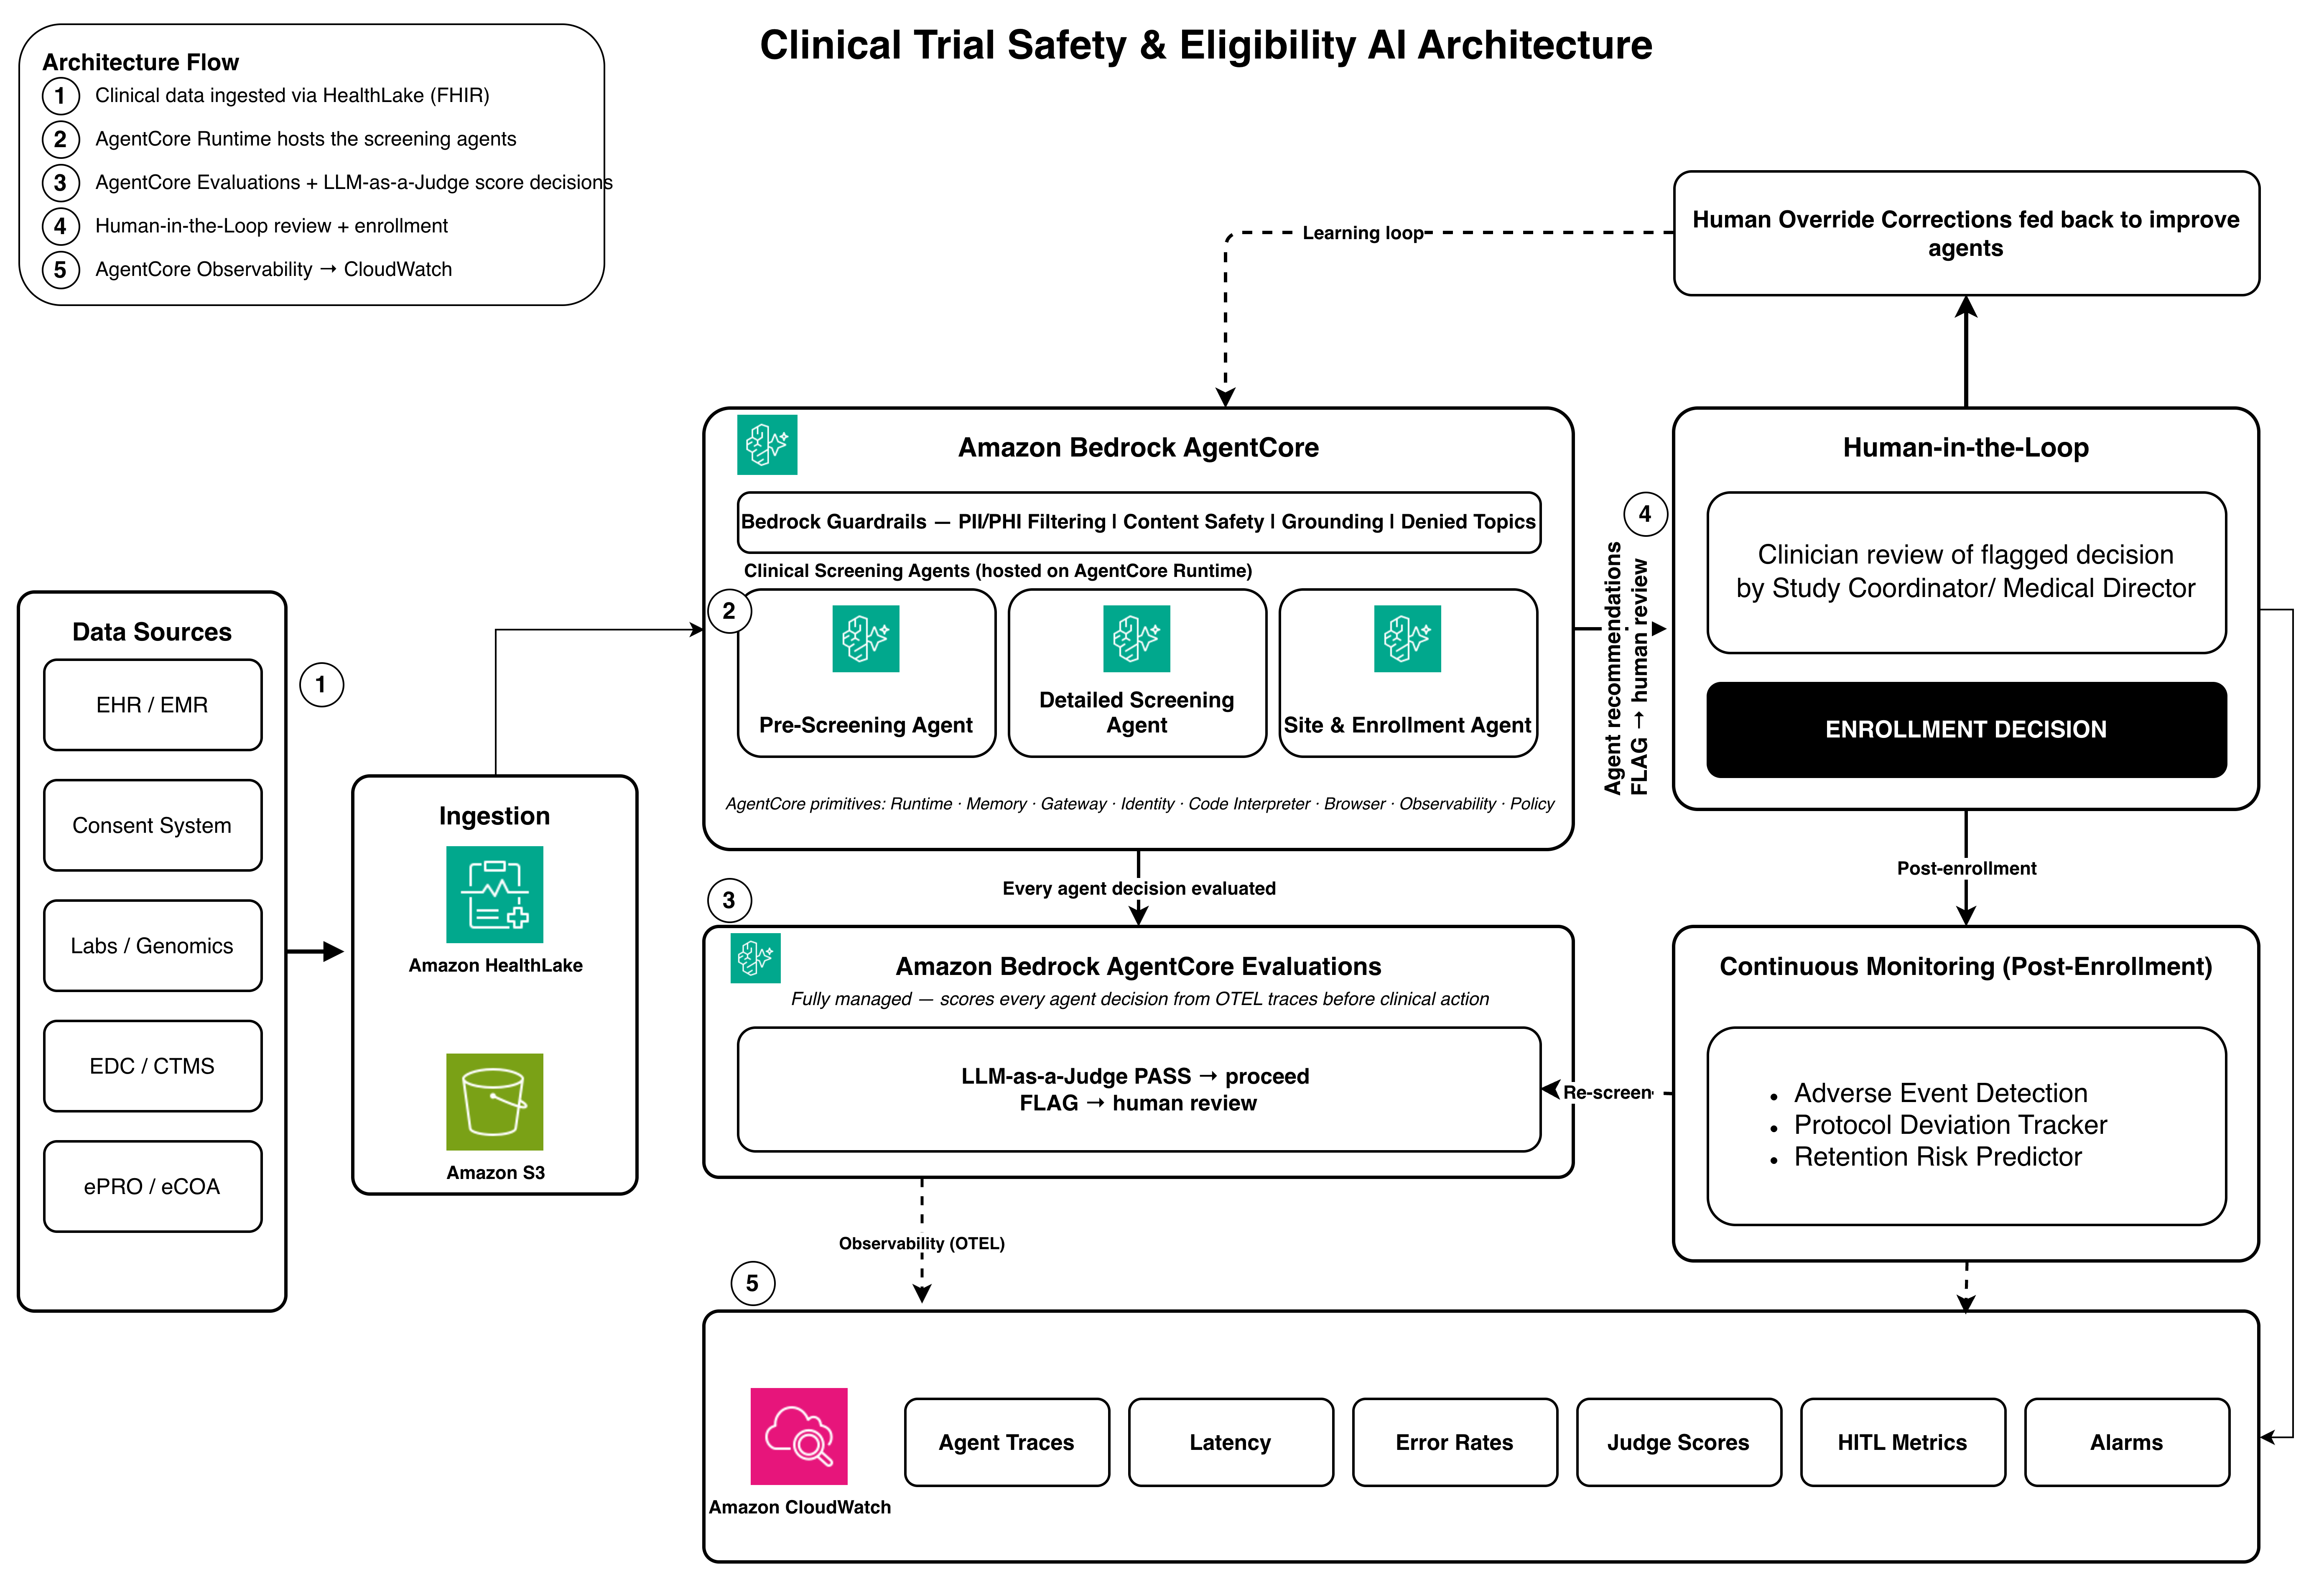
Architecture workflow
The screening pipeline operates in the following steps. Each step maps to a distinct phase of the eligibility and safety assessment, from data ingestion through clinician review and continuous monitoring.
Step 1: Clinical data ingestion
AWS HealthLake ingests patient records from EHR systems, lab portals, imaging reports, and medication histories, then normalizes them into FHIR R4 resources for standardized, queryable access.
Step 2: Agent orchestration
Amazon Bedrock AgentCore orchestrates three specialized agents, each scoped to a distinct phase of the screening pipeline. They operate within the Amazon Bedrock AgentCore Runtime, which connects to tools through MCP Gateway, maintains session memory so agents reference earlier findings without re-querying, and enforces identity-based access control for least-privilege data access. A built-in code interpreter handles dynamic calculations such as eGFR or BMI derivation.
Pre-screening agent: The first gate. It resolves three threshold questions: Is the patient’s informed consent valid and current? Does their high-level profile (age, diagnosis category, geography) align with basic enrollment parameters? Have they completed any required washout period? Patients who clear all three advance. Those who don’t receive a documented rejection citing the failing criterion.
Detailed screening agent: The core clinical reasoning engine. It walks through all inclusion and exclusion criteria, retrieving the relevant FHIR resources — Observation for labs, Condition for diagnoses, MedicationStatement for medications — and evaluating each against the protocol threshold. It also reviews organ function, adverse drug reactions, and contraindicated conditions, cross-references medications against the investigational product for interactions, and assesses the overall comorbidity profile for risk combinations no single criterion would catch. The output is a structured determination (Eligible, Ineligible, or Requires Review) with a per-criterion evidence matrix, confidence scores, and a reasoning summary citing source records.
Site & enrollment agent: Once a patient clears screening, it handles operational logistics — matching the patient to the most appropriate site by proximity, capabilities, and investigator availability, then confirming open enrollment capacity. If the preferred site is full, it identifies alternatives and flags the study coordinator.
All three agents operate behind Amazon Bedrock Guardrails, which enforce:
Step 3: LLM-as-judge evaluation
Amazon Bedrock AgentCore Evaluations scores every screening decision using a combination of built-in and custom evaluators across three dimensions:
Decisions that pass evaluation with high confidence proceed to the clinician dashboard. The system flags those that fall below quality thresholds and routes them to human review with the specific evaluation concern highlighted.
Step 4: Human-in-the-loop review and enrollment
Flagged cases and agent recommendations flow into a tiered clinical review structure:
Clinicians retain complete override capability at every stage. When a clinician overrides an agent recommendation, approving a patient the agent flagged or rejecting one it cleared, the system captures the corrected decision and the clinician’s reasoning. These corrections expand the ground truth dataset used by Amazon Bedrock AgentCore Evaluations and surface patterns that inform prompt and retrieval tuning, creating a continuous learning loop where human judgment directly improves agent performance over time.
Step 5: Observability and continuous monitoring
Amazon CloudWatch provides end-to-end observability across all agents, surfacing agent traces (step-by-step execution logs), latency metrics, error rates (failed tool calls, guardrail blocks), judge scores (pass/flag rates per agent), HITL metrics (override rates, review latency), and alarm-based escalation when safety thresholds are breached.
Although the current implementation focuses on screening and enrollment, the same agent orchestration framework, evaluation pipeline, and compliance infrastructure support future post-enrollment monitoring agents such as adverse event detection from lab results and clinical notes, protocol deviation tracking, retention risk prediction, and re-screening triggers when clinical changes affect ongoing eligibility. Each inherits the existing scoring, logging, and auditability without requiring a separate governance framework.
The screening pipeline’s credibility rests on two layers: an automated evaluation layer that scores every decision, and a human-in-the-loop (HITL) layer that gives clinicians final authority. LLM-as-Judge (Step 3) decides which cases clinicians see and how they’re prioritized. The HITL workflow (Step 4) decides how clinicians act. Together they form a continuous loop where human judgment both safeguards and improves agent performance. Using Amazon Bedrock AgentCore Evaluations, you build a framework spanning three dimensions: clinical accuracy, operational effectiveness, and safety compliance with built-in and custom evaluators that run continuously.
Clinical accuracy and reasoning
Built-in evaluators check whether the agent gets the determination right and whether its reasoning holds up: Correctness (accurate against the patient’s labs, diagnoses, and medications), Faithfulness (reasoning stays grounded in patient data and protocol, not plausible-sounding invention), Coherence (no logical contradictions across steps), Context relevance (the right protocol and records were retrieved), and Goal success rate (the full workflow ran end to end). Custom LLM-as-Judge evaluators add clinical specifics: Eligibility accuracy (each inclusion/exclusion criterion evaluated correctly) and Criteria coverage (no criteria skipped, especially safety-critical lab thresholds and restricted medications).
Operational effectiveness
Accuracy alone is insufficient, output must fit workflows where coordinators review dozens of patients daily. Helpfulness, conciseness, and relevance confirm a clear, scannable, on-topic determination. Instruction following verifies the expected structured format (patient summary, criteria checklist, determination, justification, safety flags, next steps). Tool selection and parameter accuracy check the agent invoked the right tools with correct inputs.
Safety and responsible behavior
Safety carries the strictest thresholds. Harmfulness detection flags clinically dangerous content; Stereotyping detection makes sure decisions aren’t influenced by demographics beyond protocol requirements. Both trigger immediate review. Custom evaluators target the highest-risk failures: Safety flag detection confirms every significant concern surfaced (contraindicated medications, out-of-range labs, disqualifying conditions, drug interactions), with a single miss treated as critical; Uncertainty acknowledgment makes sure the agent recommends human review on missing or ambiguous data rather than making an overconfident call.
The human-in-the-loop safeguard
When a wrong eligibility call can affect patient safety, human judgment is the final safeguard. A score below threshold routes the case to the HITL workflow.
The three agents together produce an eligibility determination with a confidence score. At trial onset, the clinician sets a confidence threshold. Cases below it or flagged by evaluation reach the clinician dashboard with the specific concern highlighted. Clinicians review the full reasoning and approve, reject, or request more information from the same interface. Their corrections are stored alongside machine-approved records, feeding back into future determinations and continuously improving accuracy.
Review and approval workflow
Review is tiered by complexity: automated pre-screening filters clearly ineligible candidates. Low-complexity cases get expedited review, medium-complexity follow standard protocols, and high-complexity edge cases escalate to senior clinicians. Cases unreviewed beyond set timeframes escalate automatically. Final enrollment decisions, low-confidence cases, experimental therapies, and complex histories require human approval. Routine high-confidence checks proceed automatically.
The system generates immutable audit records in Amazon DynamoDB for every decision, capturing clinician ID, timestamp, patient and trial IDs, outcomes, AI recommendations, and complete workflow execution history. These records are designed to support FDA 21 CFR Part 11 requirements for electronic records and signatures, providing documentation for regulatory inspections and quality assurance. Readers should consult their compliance team and conduct their own assessment. See the AWS compliance resources for further guidance.
Clinical trial data is among the most sensitive in healthcare. HIPAA, FDA 21 CFR Part 11, GxP, and GDPR require strict controls over how patient data is stored, accessed, and processed, and AI agents reasoning over that data introduce new security considerations. This solution protects data at every layer while maintaining the audit trails and privacy standards regulators require.
AWS HealthLake is HIPAA-eligible with encryption at rest and in transit, access controls, and SMART on FHIR authorization. Amazon Bedrock is HIPAA-eligible, SOC 2 attested, ISO and CSA STAR Level 2 certified, and never shares customer data with model providers. AWS PrivateLink keeps traffic off the public internet.
Amazon Bedrock AgentCore enforces agent boundaries at runtime through declarative authorization policies — readable, deterministic rules, outside application code, defining what the agent can access, invoke, and retrieve. AgentCore runs within your Amazon Virtual Private Cloud (Amazon VPC) for network isolation, and AWS CloudTrail records API calls for an immutable audit trail that can support FDA compliance requirements.
Amazon Bedrock AgentCore Evaluations scores each decision using built-in and custom evaluators with an LLM-as-a-Judge approach. Continuous sampling detects drift, and Amazon CloudWatch alerts teams when quality drops below thresholds — ongoing evidence the agent performs within validated parameters, supporting GxP with minimal manual testing.
In this post, we showed how combining the FHIR-native data foundation of AWS HealthLake
with the multi-step reasoning capabilities of Amazon Bedrock AgentCore turns manual,
fragmented clinical trial screening into an AI-assisted workflow that reduces patient matching
time from days to minutes. Clinical trial enrollment remains one of drug development’s most
resource-intensive bottlenecks, and delayed starts carry heavy financial consequences from lost
patent-protected sell time and operational burn. Clinicians receive organized evidence,
transparent reasoning, and actionable recommendations while retaining full decision authority
and audit traceability.
The impact extends beyond speed: more consistent criteria interpretation across sites, earlier
detection of safety contraindications, and lower screen failure rates. As oncology trial eligibility
criteria grow in complexity — with fewer than 5% of cancer patients enrolling under strict
requirements — this human-in-the-loop approach offers a scalable, compliance-aligned path to
faster, higher-quality recruitment.
Ready to accelerate your clinical trial operations? Take the next step:
Post Syndicated from jzb original https://lwn.net/Articles/1089501/
Security updates have been issued by AlmaLinux (.NET 10.0, .NET 9.0, 389-ds-base, attr, curl, glib2, gstreamer1-plugins-bad-free, gstreamer1-plugins-bad-free and gstreamer1-plugins-ugly-free, gstreamer1-plugins-good, gstreamer1-plugins-ugly-free, haproxy, kernel, libssh, libXfont2, nodejs22, pam, php, php8.4, sg3_utils, and unbound), Debian (librabbitmq, ruby-grape, spip, srt, and swift), Fedora (GitPython, lemonldap-ng, libgit2, libnfs, perl-Imager, perl-List-SomeUtils-XS, python3.12, python3.14, and radsecproxy), Oracle (.NET 10.0, 389-ds-base, 389-ds:1.4, bind, curl, gstreamer1-plugins-bad-free, gstreamer1-plugins-bad-free and gstreamer1-plugins-ugly-free, gstreamer1-plugins-good, gstreamer1-plugins-ugly-free, haproxy, libssh, libXfont2, nodejs22, nodejs:22, pcp, and unbound), Red Hat (golang, grafana, grafana-pcp, osbuild-composer, and rhc), SUSE (erlang, forgejo-cli, go1.25, go1.26, htop, python-pypdf2, python313-tablib, and snphost), and Ubuntu (c3p0, dotnet8, dotnet10, kernel, linux, linux-aws, linux-aws-fips, linux-aws-hwe, linux-fips, linux-hwe,
linux-kvm, linux, linux-aws, linux-aws-fips, linux-azure, linux-fips, linux-gcp,
linux-gcp-6.8, linux-gcp-fips, linux-gkeop, linux-oracle, linux-realtime,
linux-realtime-6.8, linux-xilinx, linux-hwe-7.0, linux-oracle, linux-oracle-6.17, and linux-oracle-6.8).
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=D-Q8bxxydVE
Post Syndicated from Cássio De Alcântara original https://www.rapid7.com/blog/post/c-licencias-online-partnership-accelerates-latam-cybersecurity-maturity-latin-america
Cássio De Alcântara is Director, LATAM Sales at Rapid7.
Across Latin America, organizations are embracing cloud, AI, and digital transformation to drive innovation and business growth. These technologies create new opportunities, but also introduce greater complexity and expanding attack surfaces.
In this environment, security leaders are being asked to understand where risk exists across increasingly distributed environments and quickly eliminate blind spots like Shadow IT and Shadow AI – all without adding operational complexity.
To help security leaders and practitioners address this complexity, Rapid7 is excited to announce a new strategic distribution partnership with Licencias OnLine (LOL) across Latin America.
In order to keep day-to-day business operations moving, organizations need security solutions that not only protect critical assets but also support innovation, regulatory compliance, and long-term digital transformation.
Rapid7’s AI-powered cybersecurity operations platform helps organizations strengthen cyber resilience by unifying continuous exposure management, AI-driven threat detection and response, and security automation. By connecting security data across endpoint, cloud, identity, and infrastructure environments, organizations leverage one platform to gain the visibility to reduce risk and act with confidence.
Success in today’s fragmented cybersecurity environments depends on a strong ecosystem of partners who can help organizations implement, optimize, and maximize the value of unified security operations.
This is where Licencias OnLine comes in. With a strong, well-established presence across Latin America, deep cybersecurity expertise, and a highly specialized channel ecosystem, Licencias OnLine brings the local knowledge, technical enablement, and operational agility needed to help partners grow their cybersecurity practices and deliver greater value to customers.
Together, Rapid7 and Licencias OnLine will invest in technical training, partner enablement, joint marketing initiatives, and go-to-market programs that help partners expand managed security services, strengthen customer relationships, and accelerate business growth across the region.
As organizations across Latin America continue to modernize their IT environments, they should have access to security operations that are integrated, intelligent, and designed for today’s AI-powered threat landscape.
Rapid7’s open platform supports this approach through hundreds of technology integrations that help organizations eliminate security silos, improve visibility across their attack surfaces, and automate response workflows. This enables security teams to reduce operational complexity while improving cybersecurity program maturity.
By combining Rapid7’s global cybersecurity innovation with Licencias OnLine’s regional expertise and trusted partner network, this new alliance will make it easier for organizations across Latin America to strengthen cyber resilience while enabling partners to see greater success through measurable business outcomes.
We’re excited to begin this next chapter together and look forward to supporting our partners as they help customers build stronger, more resilient security operations across the region.
Ready to grow with Rapid7? Discover how Rapid7 and Licencias OnLine are helping partners accelerate cybersecurity maturity across Latin America.
Post Syndicated from D Surya Sai original https://aws.amazon.com/blogs/compute/set-up-your-ai-coding-agent-to-build-with-aws-step-functions/
You want to build an AWS Step Functions workflow, and you have an AI coding agent open in your terminal or IDE. But the agent doesn’t know about Amazon States Language (ASL), service integrations, or how to deploy state machines. Before you can start, you need to find the right Model Context Protocol (MCP) server package, figure out the configuration format for your specific agent, and set up credentials.
AWS Step Functions has added a “Copy agent prompt” button to the AWS Step Functions console that removes this setup entirely. You choose the button, paste the prompt into your agent, and the agent configures itself with Serverless skills and an MCP server. You can start building workflows with natural language immediately. The feature works with Claude Code, Kiro CLI, Cursor, GitHub Copilot, Codex, Devin Desktop, OpenCode, and any other MCP-compatible agent.
The button appears in three places in the Step Functions console:
Here’s an example from the Create State Machine flow:
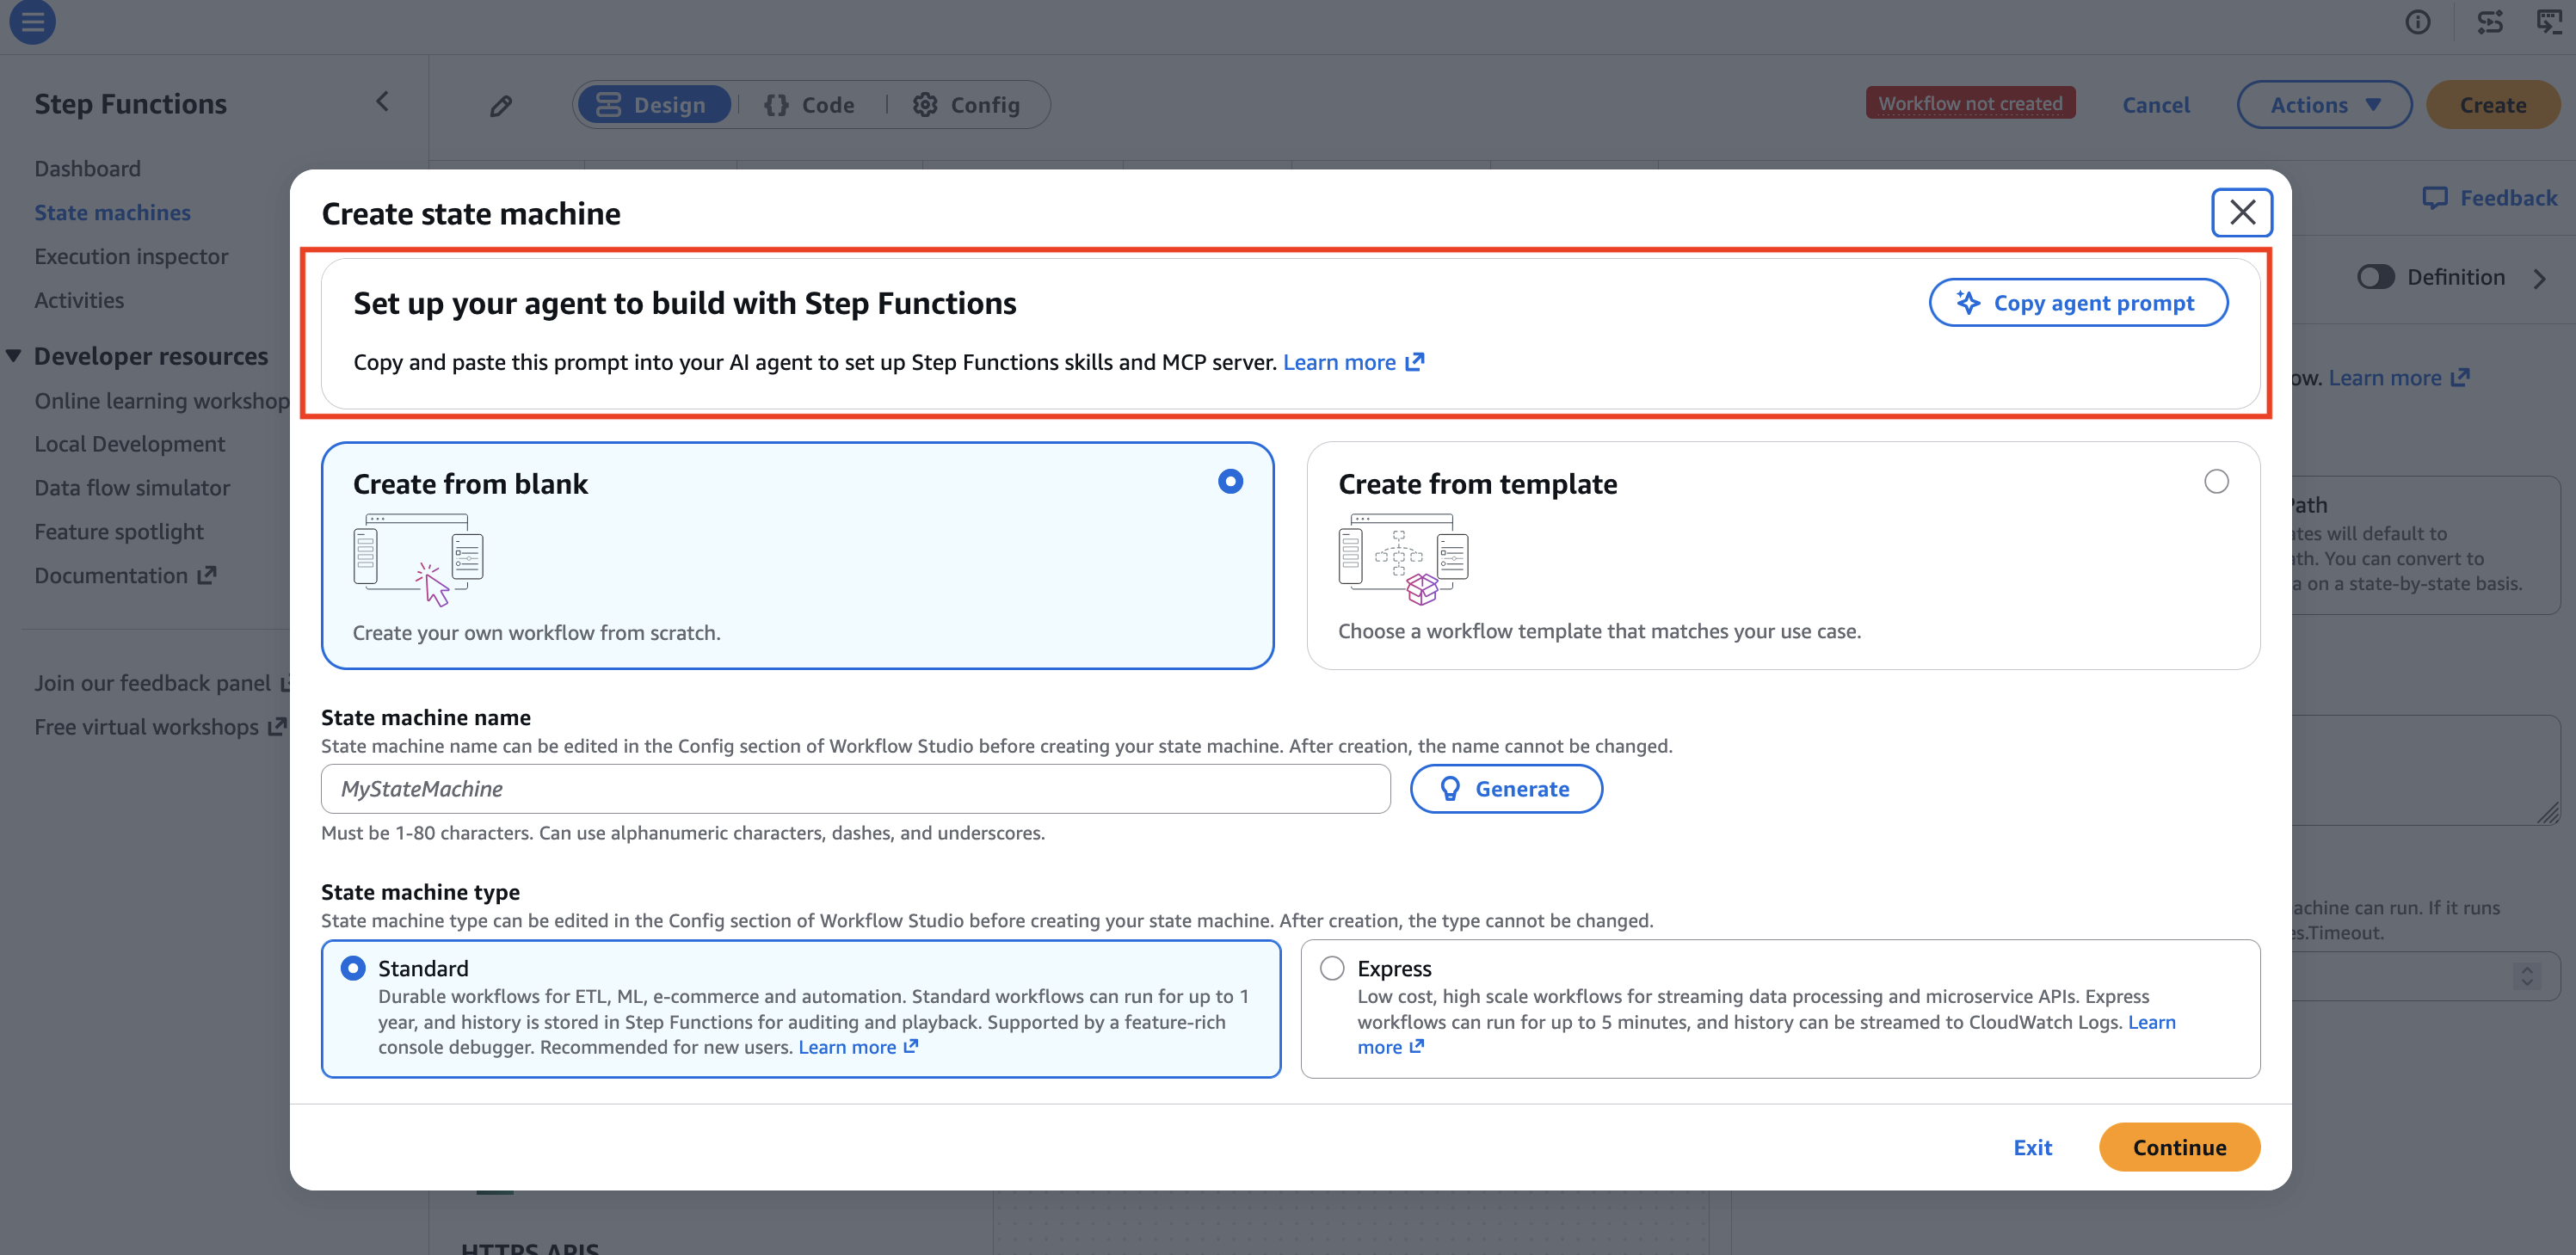
Figure 1: Step Functions console modal showing the Copy agent prompt
The copied prompt is a fetch instruction that points to a setup guide hosted on AWS documentation. You paste it into your agent, and the agent installs two things:
AWS Serverless skill (from the Agent Toolkit for AWS) provides your agent with deep context on Step Functions. It includes how to write ASL, structure workflows with retries and error handling, choose between Standard and Express workflow types, implement patterns like saga orchestration and parallel fan-out, and deploy using AWS Serverless Application Model (AWS SAM) or AWS Cloud Development Kit (AWS CDK).
AWS Serverless MCP Server gives your agent direct access to AWS. Through the Model Context Protocol, your agent can create and update state machines, start and describe executions, inspect workflow history, and manage resources in your account.
The setup guide auto-detects your agent and provides the correct configuration format:
claude mcp add.~/.kiro/settings/mcp.json.codex mcp add..cursor/mcp.json..vscode/mcp.json..devin/mcp_config.json.~/.config/opencode/opencode.jsonc.If you use a different MCP-compatible agent, the guide provides a generic JSON configuration block you can add to your agent’s config file.
Once your agent is configured, you can describe workflows in natural language, and the agent produces valid, deployable state machines. Here are a few examples:
Order processing with compensation: “Build a workflow that validates a payment, reserves inventory and sends a confirmation email. If payment fails, release the inventory reservation.”
Parallel fan-out: “Create an Express workflow that calls three AWS Lambda functions in parallel, waits for all to complete, and merges the results into a single response.”
Human approval gate: “Add a step that pauses the workflow and waits for a manager to approve before proceeding with the deployment.”
Error handling: “Add retry with exponential backoff and a maximum of three attempts to the payment processing step. If all retries fail, route to a fallback notification step.”
Because the agent has the MCP server connected, it can also deploy the workflow directly to your account, start test executions, and inspect the results without leaving the agent interface.
Always current: The Agent Toolkit for AWS content stays up to date as Step Functions adds new features, integrations, and patterns. When you run the prompt, your agent gets the latest skills and configurations automatically.
No context switching: You stay in your agent’s interface for the entire workflow: design, build, deploy, test, and iterate. No switching between the console, documentation, and your editor.
Works with your existing credentials: The MCP server uses your local AWS profile. No new AWS Identity and Access Management (IAM) roles or permissions are required beyond what you already use for Step Functions development.
Agent-agnostic: Whether you use Claude Code, Kiro, Cursor, Copilot, or another tool, the same button and prompt works. You don’t need to find agent-specific setup instructions.
This feature is available in all commercial AWS Regions at no additional cost. To learn more about the setup process, see the agent setup guide. For more on the Agent Toolkit for AWS, see the GitHub repository. For AWS MCP Servers, see the documentation.
We’d like to hear how you use this feature. Tell us about it in the comments.
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/ice-collecting-dna-samples.html
ICE collected nearly a million DNA samples last year.
Post Syndicated from xkcd.com original https://xkcd.com/3287/
Post Syndicated from Cliff Robinson original https://www.servethehome.com/qualcomm-modular-amd-open-sourced-at-modcon-2026/
Qualcomm’s Modular software is now open-source as a big announcement from ModCon 2026 and an unexpected guest made an appearance
The post Qualcomm Modular Open-Sourced at ModCon 2026 appeared first on ServeTheHome.
Post Syndicated from corbet original https://lwn.net/Articles/1089386/
Version
154.0 of the Firefox browser has been released. Changes include
extending local network access protections to WebSocket connections, more
flexible, per-site configuration of cookie and data clearing, and more.
Post Syndicated from Nishant Mainro original https://aws.amazon.com/blogs/security/implement-custom-authentication-for-tools-integration-using-request-lambda-interceptor-in-agentcore-gateway/
When deploying AI agents with Amazon Bedrock AgentCore, organizations benefit from built-in modern support for OAuth 2.0, AWS Identity and Access Management (IAM), and API key authentication through Amazon Bedrock AgentCore Gateway. However, some enterprise environments still use legacy authentication mechanisms such as HTTP Basic Authentication (Basic Auth) (RFC 7617). The extensible architecture of AgentCore Gateway enables support for these authentication mechanisms through a request Lambda interceptor—custom code that runs each time an agent calls a tool.
In this post, we show you how to use a request Lambda interceptor to authenticate to a downstream tool API using system credentials, retrieving a service account credential from AWS Secrets Manager and constructing a Basic Auth header. This design keeps credentials isolated from the agent, designed to mitigate exposure through model-driven behavior such as prompt injection.
Important: Basic Auth is an antiquated technology that transmits credentials as Base64-encoded text and should not be used as a long-term authentication strategy. AWS recommends modernizing to OAuth 2.0, SAML, OpenID Connect, or IAM where possible. However, some organizations with legacy workloads choose to decouple authentication modernization from their agentic AI adoption, addressing each on independent timelines. If your environment requires Basic Auth integration as an interim measure, consult your AWS Solutions Architect to evaluate the security trade-offs before proceeding. We’re providing this post as a reusable implementation, but it shouldn’t be construed as an endorsement of Basic Auth, or considered suitable as a long-term solution.
The solution uses a request Lambda interceptor in AgentCore Gateway to retrieve system credentials and construct a Basic Auth header for the downstream tool API. Figure 1 shows the end-to-end flow.
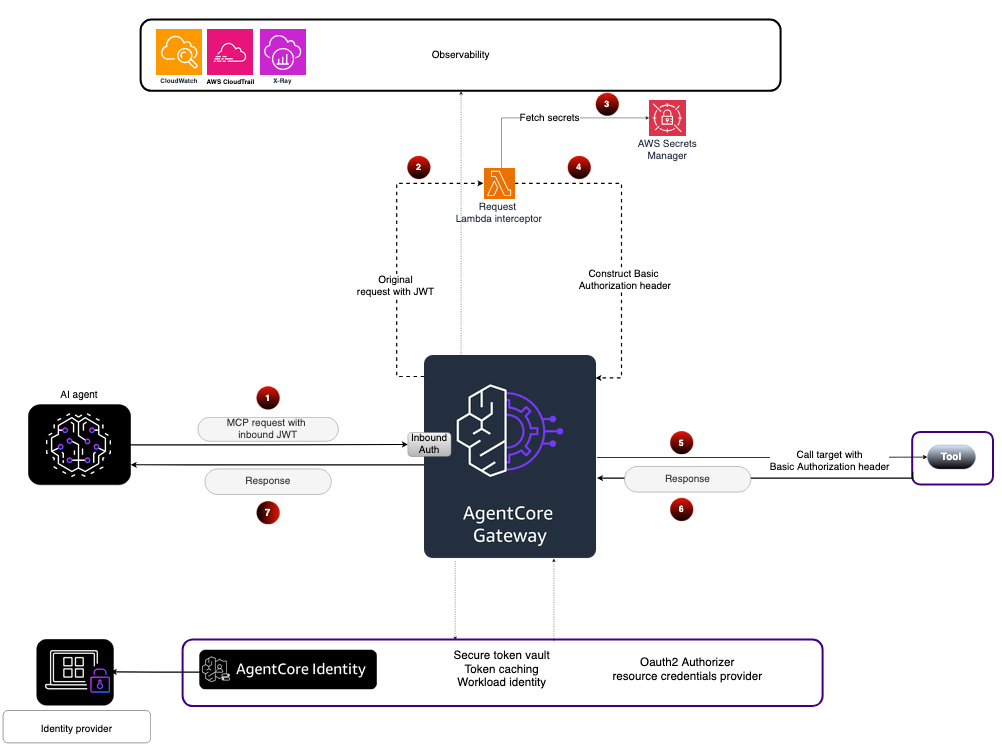
Figure 1: Solution workflow
Note: The system credential stored in Secrets Manager corresponds to a service account in Active Directory (AD). The credential lifecycle requires a one-time manual seed: a system administrator creates the service account in AD and stores the same initial credential in Secrets Manager (necessary because Secrets Manager can’t read a password back from AD). As a security best practice, trigger an immediate rotation after seeding to retire the human-known password using the built-in capabilities of Secrets Manager. From that point forward, Secrets Manager automates the rotation process, periodically generates a new password, and updates both Secrets Manager and AD simultaneously. This eliminates manual credential management in either system. At runtime, the request Lambda interceptor retrieves the current credential from Secrets Manager and presents it to the downstream tool, which validates it against AD. For implementation details on keeping both stores synchronized, see Rotate Active Directory credentials stored in AWS Secrets Manager.
The following steps walk through configuring the request Lambda interceptor and implementing the core of the authentication transformation logic. You can find the complete sample code at Implementing custom authentication for tools integration using Request Lambda Interceptor.
Configure the AgentCore gateway to invoke a request Lambda interceptor for authentication transformation before forwarding the request to the downstream tool.
Important: You must enable
passRequestHeadersconfiguration. Without it, the request Lambda interceptor can’t receive the request header containing the inbound JWT, and the authentication pattern described in this post will not work.
The following example shows the gateway configuration:
The interceptor independently validates the JWT signature as a defense-in-depth measure, protecting against scenarios where the request Lambda interceptor could be invoked through a path that bypasses gateway validation. It fetches the identity provider’s JSON Web Key Set (JWKS) (cached across warm Lambda invocations to avoid repeated network calls), verifies the token’s signature, expiration, and issuer, then returns the decoded claims.
The following code demonstrates JWT validation:
The interceptor retrieves the system service account credential from Secrets Manager. This credential authenticates the AI agent to the downstream tool. The secret is encrypted with a customer-managed AWS Key Management Service (AWS KMS) key and cached in memory for the configured time-to-live (TTL) to minimize API calls while ensuring rotated credentials are picked up promptly.
The following code retrieves the credential from Secrets Manager:
IAM permissions: The interceptor’s execution role requires secretsmanager:GetSecretValue scoped to the specific secret Amazon Resource Name (ARN), and kms:Decrypt scoped to the KMS key used to encrypt it. Follow the principle of least privilege by restricting the resource ARN rather than using wildcards.
Note: The agent doesn’t have access to Secrets Manager. Only the request Lambda interceptor—a deterministic function not influenced by model behavior—retrieves credentials. This isolation is designed to mitigate the risk of adversarial prompts instructing the model to access or exfiltrate authentication credentials, even if the agent is compromised.
The request Lambda interceptor constructs the Basic Auth header using the system credential retrieved for the downstream tool.
The following code shows the core transformation logic.
A request Lambda interceptor in Amazon Bedrock AgentCore Gateway can bridge the gap between the authentication patterns supported by the gateway and the authentication requirements of legacy tool APIs that haven’t yet migrated to modern authentication standards. As demonstrated in this post, the interceptor validates the inbound JWT, retrieves system credentials from Secrets Manager, and constructs the downstream tool’s Basic Auth header without modifying tool schemas or agent implementation.
This approach is an interim integration pattern, not a target architecture. It introduces a credential that must be synchronized between Secrets Manager and the tool’s identity store (such as Active Directory), adding operational overhead for rotation, drift detection, and lifecycle management. The recommended path is to modernize the downstream tool to accept OAuth 2.0, SAML, or OpenID Connect, eliminating stored credentials entirely. Until that modernization is complete, the interceptor isolates credential handling from the agent runtime, designed to help ensure that the agent—a non-deterministic system influenced by user prompts—does not have access to authentication secrets.
If you have feedback about this post, submit comments in the Comments section below.
Post Syndicated from Kaushik Krishnan original https://aws.amazon.com/blogs/big-data/querying-raw-log-data-using-sql-and-ppl-with-the-optimized-engine-in-amazon-opensearch-service/
In this post, you learn how to run fast analytical queries directly against raw log and trace data in Amazon OpenSearch Service using PPL and SQL.
Amazon OpenSearch Service is a fully managed service that helps you deploy, scale, and operate OpenSearch, the open source suite for search, analytics, and observability in the AWS Cloud. OpenSearch Service powers search and real-time analytics workloads, from lexical and hybrid search to log analytics and observability. This post focuses on log analytics, and on a practical question: how much analytical work can you do directly against raw log and trace data, without moving it or reshaping it first?
The new optimized engine in OpenSearch Service answers that question: you can point Piped Processing Language (PPL) and Structured Query Language (SQL) queries at raw log and trace data. The engine returns aggregations, filters, and scans over billions of events on the data exactly as you ingested it. In this post, you follow a single incident investigation, one query at a time. You see how the engine answers each new question, from multi-dimensional breakdowns and latency distributions to error rates and fleet sizing. No precomputed structure sits behind the results.
The optimized engine stores data in the columnar Apache Parquet format and runs queries through Apache DataFusion, a vectorized execution engine, with Apache Calcite planning each query. Because the engine stores data in columns, an analytical query reads only the columns it touches and processes their values in batches, instead of reading each matching document in full. Alongside the columnar format, the engine also keeps an inverted index on the same data, so the query planner routes each operation to the path that serves it best: the columnar engine for aggregations and analytical scans, and the inverted index for selective search and filtering.
You ingest your logs and traces through the same Bulk API and clients you use today, and you write PPL or SQL against them as they land.
The following walkthrough traces a common observability use case, root-cause analysis during a live incident, from the perspective of a site reliability engineer (SRE). The engineer notices elevated latency and a handful of error alerts, with nothing that points to a clear cause. No existing dashboard covers this particular shape of problem, so the engineer opens Amazon OpenSearch Service and starts asking questions of the raw trace data, letting each answer decide the next one. PPL suits this work well. Each command transforms the data and passes it to the next, so the engineer reads a query left to right the same way they think through the investigation.
The walkthrough uses generated OpenTelemetry (OTEL) data from a synthetic load generator, at billion-document scale. The focus is the query capability, that is, what the engineer can express and retrieve directly from raw spans, rather than the specific values in each result.
The first question in any investigation is how widespread the signal is. The engineer breaks errors down across service, HTTP method, and cloud Region in a single pass over roughly 1.1 billion spans.
In plain terms, this query answers the engineer’s first question: where are the failures happening? It counts the error spans and breaks them down by service, HTTP method, and AWS Region in a single pass. Rather than guessing which service to open first, the engineer gets a ranked list of the hardest-hit combinations to investigate.
| errors | total_count | avg_ns | serviceName | http_method | cloud_region |
| 730 | 112,436 | 41,246,806 | export-service | GET | us-west-2 |
| 722 | 111,215 | 41,000,227 | catalog-service | PUT | eu-central-1 |
| 704 | 112,051 | 41,295,539 | image-service | PATCH | us-west-2 |
| 612 | 93,214 | 41,451,145 | healthcheck-service | PUT | us-east-1 |
| 609 | 94,314 | 41,418,897 | auth-service | POST | us-east-1 |
| 609 | 94,414 | 41,447,444 | email-service | PATCH | ap-northeast-1 |
| 593 | 89,726 | 41,047,114 | payment-service | PUT | eu-central-1 |
| 581 | 89,854 | 41,195,643 | file-service | PUT | ap-northeast-1 |
The errors spread across services, methods, and Regions, which points to a systemic pattern rather than a single misbehaving service.
The spread could still reflect one saturated node or a fleet-wide condition. To tell the two apart, the engineer groups failures by exception type, service, and host across the entire index, with no time filter to narrow the scan.
| total_count | exception_type | serviceName | host_name |
| 6 | DeadlockDetectedException | notification-service | ip-10-0-16-34 |
| 6 | IllegalStateException | api-gateway | ip-10-0-180-234 |
| 6 | FileNotFoundException | cart-service | ip-10-0-90-162 |
| 6 | ConnectionRefusedException | feature-flag-service | ip-10-0-8-123 |
| 5 | TimeoutException | auth-service | ip-10-0-97-78 |
| 5 | ConcurrentModificationException | order-service | ip-10-0-165-15 |
| 5 | TimeoutException | coupon-service | ip-10-0-158-25 |
In this sample the counts are low and every row lands on a different host, so no single node stands out. This points to a fleet-wide pattern rather than one bad machine. On production data the same query makes the distinction directly: a code-level bug shows up across many hosts, whereas a single failing node concentrates its errors on one host_name.
Next, the engineer pulls a latency profile for each service. This includes count, average, minimum, and maximum duration, to see how each one behaves and how wide the spread runs.
| serviceName | total_count | avg (ns) | min (ns) | max (ns) |
| event-bus | 11,087,263 | 41,249,552 | 26,113 | 9,304,132,159 |
| scheduler-service | 9,175,964 | 41,251,927 | 21,919 | 13,432,040,933 |
| cdn-service | 9,173,572 | 41,225,385 | 23,468 | 13,768,293,306 |
| ml-inference | 9,036,753 | 41,289,101 | 40,410 | 14,625,084,517 |
| compliance-service | 8,274,635 | 41,294,694 | 41,915 | 7,462,983,016 |
| metrics-collector | 7,804,234 | 41,334,728 | 16,535 | 23,228,217,669 |
| notification-service | 7,688,714 | 41,204,635 | 51,562 | 8,695,311,374 |
| image-service | 7,674,406 | 41,248,069 | 47,473 | 15,350,500,299 |
This gives the engineer a latency fingerprint for each service: the averages sit near 41 milliseconds. But the multi-second maxima reveal a long tail consistent with requests queuing behind a slow dependency.
To track a service-level objective, the engineer computes the error rate (errors against total requests) per service. The query uses an inline conditional, followed by a grouped sum and count, and a final division to produce the error rate.
| errors | total_count | error_pct | serviceName |
| 699,358 | 22,415,308 | 3.12 | payment-service |
| 647,811 | 26,880,140 | 2.41 | checkout-service |
| 562,811 | 30,096,860 | 1.87 | auth-service |
| 316,192 | 24,510,990 | 1.29 | cart-service |
| 288,314 | 30,671,704 | 0.94 | order-service |
| 202,612 | 28,140,552 | 0.72 | search-service |
| 186,012 | 33,820,415 | 0.55 | catalog-service |
| 134,722 | 35,453,247 | 0.38 | image-service |
The engineer defines the error-rate metric in the query itself, and the engine computes it across the full index. The busiest paths, payment and checkout, run near 3 percent, whereas some services stay below 1 percent.
Finally, the engineer sizes how much of the fleet each service spans, a capacity and impact question, and switches from PPL to SQL to express it.
| serviceName | total_count | hosts |
| ml-inference | 35,481,688 | 2,535 |
| image-service | 35,453,247 | 2,491 |
| email-service | 35,443,569 | 2,517 |
| shipping-service | 30,700,372 | 2,438 |
| translation-service | 30,490,570 | 2,502 |
| auth-service | 30,096,860 | 2,466 |
| chat-service | 25,564,111 | 2,449 |
| recommendation-service | 25,366,844 | 2,483 |
The query runs a COUNT(DISTINCT) over a high-cardinality field at billion-row scale, and switching languages mid-investigation costs the engineer nothing more than writing SQL instead of PPL. The host counts cluster in the approximately 2,400–2,540 range, so each service runs across a broad slice of the fleet. That confirms the earlier finding: the errors reflect a fleet-wide pattern, not a single node.
The engineer asked five questions and ran five queries, and each answer shaped the next. The optimized engine served every query directly from raw trace data, across both PPL and SQL, without a rollup table or precomputed summary behind any result.
You don’t need a separate tool to run the queries in this walkthrough.
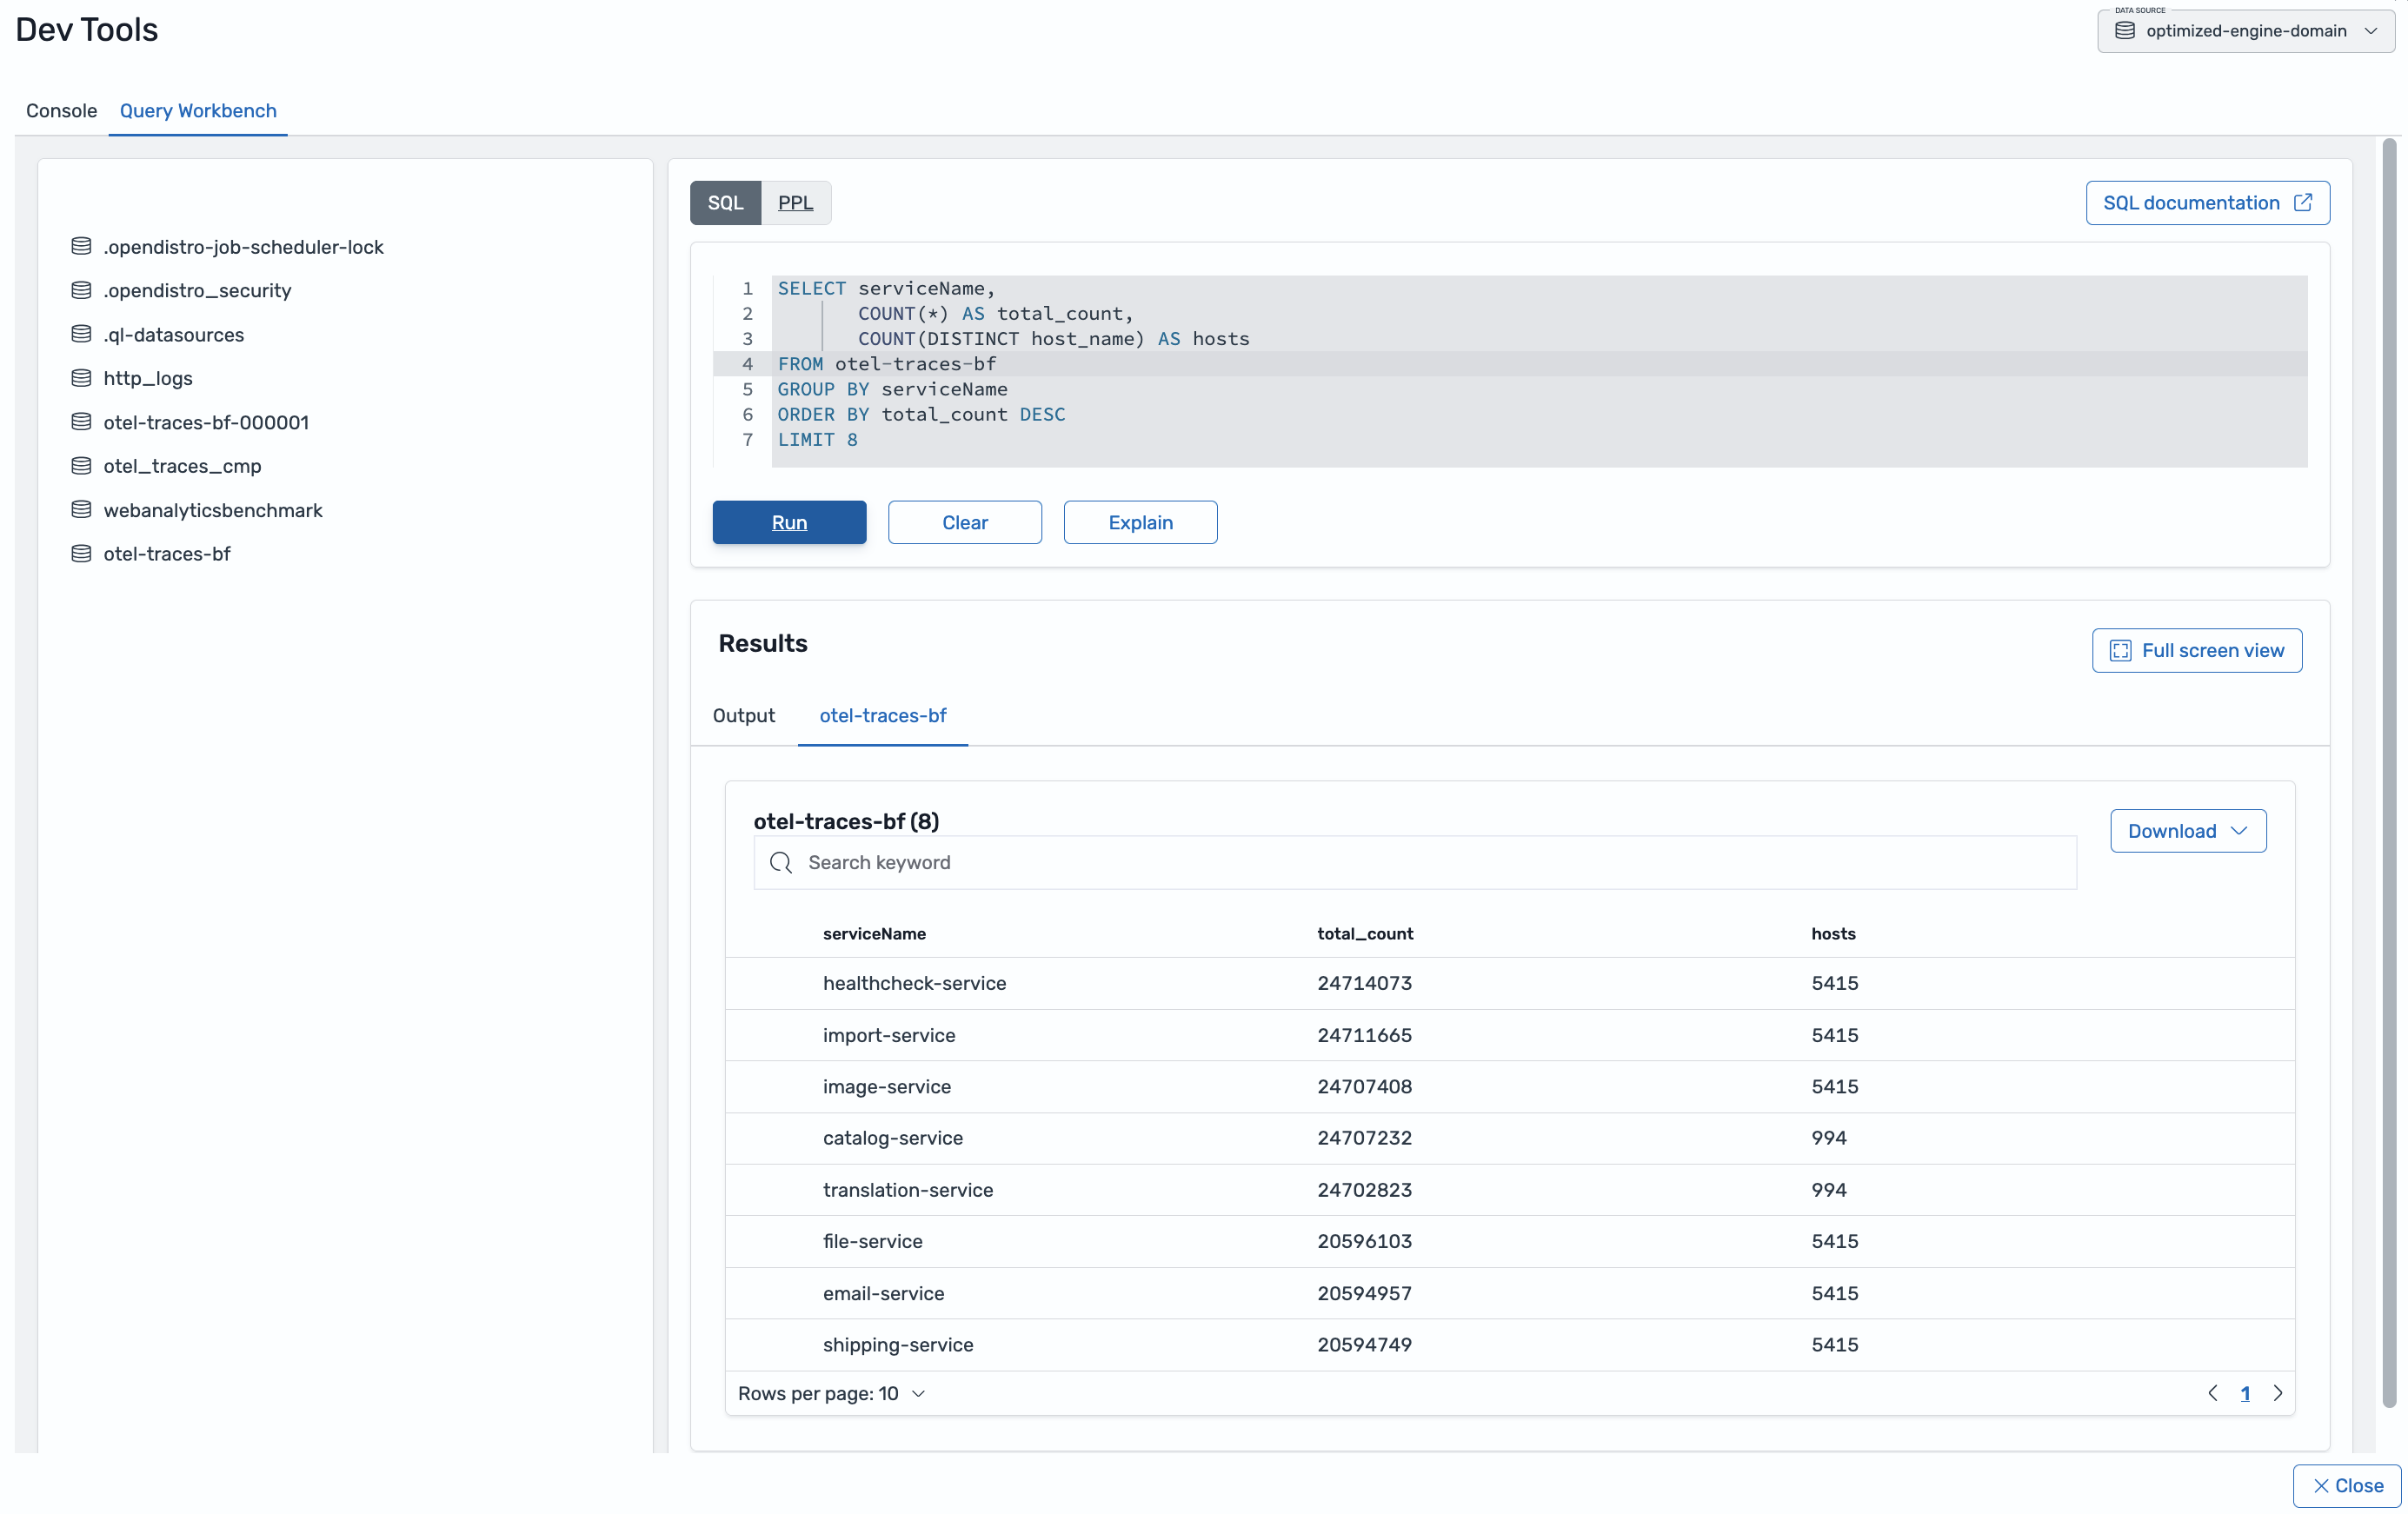
Figure 1: Investigation queries and results grid in Query Workbench
Query Workbench in OpenSearch Dashboards UI gives you a dedicated editor for PPL and SQL. You write a query, run it, and read the results in a grid, using the same queries shown throughout this post. When you want to move from a written query to interactive exploration, Discover runs the same PPL and SQL against your indexes. In Discover, you can filter, expand fields, and drill into individual documents without leaving the page. The same query language works in both places, so you can start an investigation in Discover and carry it into Query Workbench, or the reverse, without rewriting anything.
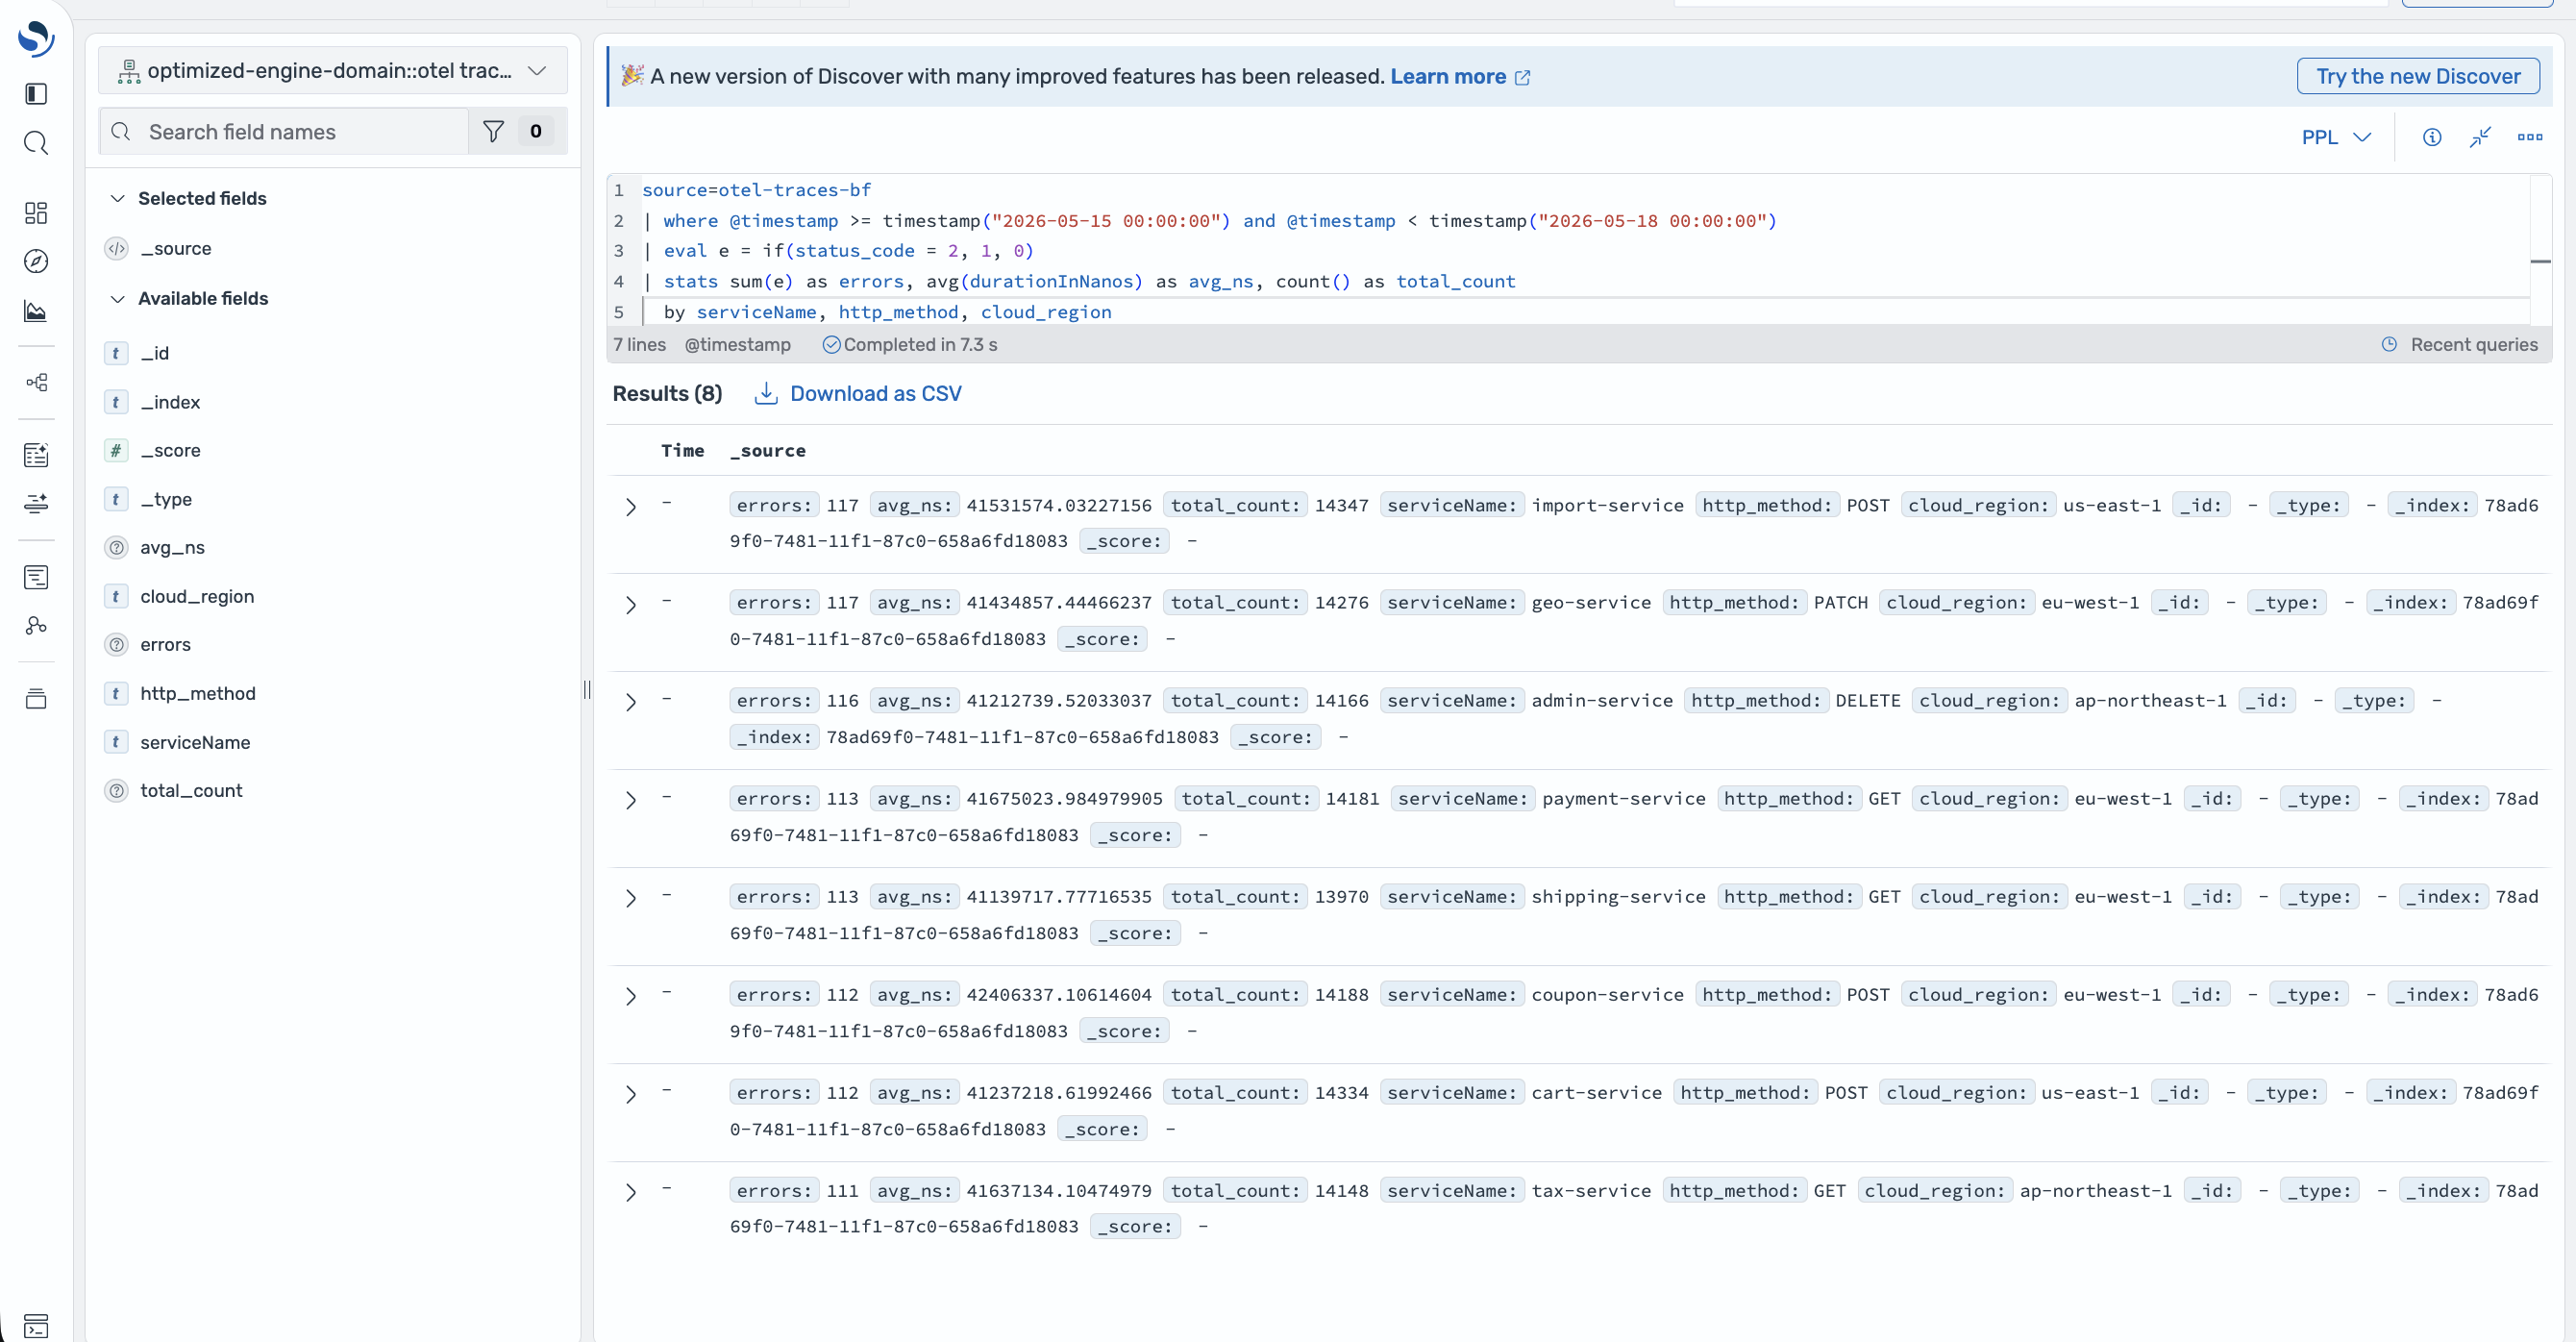
Figure 2: PPL query and field list in Discover
Querying raw data directly only helps if you can afford to keep the raw data. The optimized engine compresses observability data up to 70 percent more efficiently than the default General Purpose engine. That compression turns “keep everything and query it directly” into a practical default. You retain full-fidelity data for the questions you cannot predict in advance. You also pay less to store it than you would to store the raw JSON.
To try the optimized engine, create an Amazon OpenSearch Service domain running OpenSearch 3.5 or later. Then select the Observability use case during setup, which provisions the domain with the optimized engine.
To learn more about configuring and using the optimized engine, see Optimized for Log Analytics in the Amazon OpenSearch Service documentation. For an overview of the service, visit Amazon OpenSearch Service Log Analytics.
For more information, see the blog post Run log analytics for a fraction of the cost with the new engine for Amazon OpenSearch Service.
Give it a try and send feedback to AWS re:Post for Amazon OpenSearch Service or through your usual AWS Support contacts.
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/3fCogmuPgeo
Post Syndicated from Michael Fuller original https://aws.amazon.com/blogs/security/security-hub-extended-adds-supply-chain-security-as-its-tenth-category/
Since February, we’ve grown AWS Security Hub Extended from 14 curated partners across 9 categories to 23 partners across 10. At Black Hat this month, 14 of those partners were at the Amazon Web Services (AWS) booth demoing live. Four of those partners delivered theater talks and ten were featured on SecurityLive streaming. We hosted a partner reception that brought our leadership together with partner executives to plan what comes next. These are companies investing real engineering and real go-to-market (GTM) alongside us, and increasingly with each other, because the model resonates with the customers they’re talking to every day. The most common question we heard at the booth was when Supply Chain Security was coming.
It’s here. And that’s the thing I want to spend the most time on today, because it’s the category customers keep asking us about.
Software supply chain risk has moved from a security-team concern to a board-level conversation. SolarWinds showed what happens when a build system is compromised. Log4j showed what a single transitive dependency vulnerability can do at global scale. The xz utils backdoor showed the patience of a maintainer-compromise attack executed over years. Each demonstrated a different dimension of the same problem, and the pace is accelerating. Attackers know that a fast way into an enterprise is through the open source packages that enterprise unknowingly trust.
Every customer I talked to at Black Hat had this on their risk register. Most still hadn’t operationalized a solution, because doing so meant a standalone deployment, a new contract, a new console, and integration work their security team couldn’t prioritize. That’s the friction we aim to remove.
Security Hub Extended now offers Supply Chain Security with Chainguard and Socket as the curated partners. Supply Chain Security uses the same model as everything else in Extended. Every offering has pay-as-you-go pricing, one bill, no required long-term commitment. For enterprises that prefer to continue using the procurement process they always have, Security Hub Extended Private Offers are also available. These are committed term agreements with deeper discounts, the ability to aggregate spend across partners on a single AWS bill, and both monthly and annual payment options throughout the term. You pick the path that fits how you buy.
Chainguard gives you open source dependencies rebuilt from source in a hardened, verified build process, so what enters your environment is malware-resistant and provenance-backed. Their research shows that rebuilding from source would have stopped 98% of known malicious packages from ever reaching production. If you can’t verify the source, it never appears in the Chainguard repository. That’s the filter between the public registry and your developers.
Socket analyzes the actual behavior of open source packages to block malicious dependencies at the time of install. Not after a Common Vulnerability and Exposures (CVE) is published days or weeks later. At the moment the package tries to land in your environment, Socket flags it based on what it does, not what a database says about it. Its reachability analysis then tells you which vulnerabilities are exploitable from your code instead of drowning your team in noise. You pay for the distinct packages you check, not for how often your builds run.
Together, Chainguard and Socket cover the two questions that matter:
Chainguard helps secure the foundation your code is built on. Socket secures the packages you pull into it. Both help protect your software supply chain regardless of where you deploy—across clouds or on-premises. Activate both through Security Hub Extended and their findings flow into Security Hub in OCSF (Open Cybersecurity Schema Framework) alongside everything else, so a supply chain risk is correlated and prioritized next to your endpoint, identity, and cloud signals. From there, it routes out to the downstream tools you’ve already integrated, so it fits the pipeline your builders run today.
Every partner in Security Hub Extended is here because customers told us they needed that capability and that specific solution was already working for them. We add categories because the threat landscape evolves, and we add partners because customers point us to who’s solving those problems well. The goal is straightforward: Simplify adopting the security solutions your peers are already succeeding with, through the AWS relationship you already have.
The full set today spans endpoint, identity, email, network, data, browser, cloud, AI, security operations, and now supply chain. The 23 curated partners are 7AI, Britive, Chainguard, CrowdStrike, Cyera, Island, LayerX, Native Security, Noma, Okta, Oligo, Opti, Palo Alto Networks, Proofpoint, SailPoint, SentinelOne, Socket, Splunk, Sublime, Upwind, Varonis, Zenity, and Zscaler.
Our focus now is deepening integrations and reducing activation friction so these solutions work together, not in isolation. That’s where the real value compounds.
Everything I’ve described so far is the commercial model working: Customers buying best-of-breed security through one AWS relationship with the flexibility they expect. But the bigger vision is the integration layer that makes these tools genuinely better together, not just easier to buy together.
The integration we’re most focused on is cross-partner correlation, turning signals from an endpoint solution, an identity solution, and a cloud solution into one exposure and one attack path instead of three disconnected alerts. Right alongside that, we’re dramatically reducing the activation, deployment, and integration friction so customers go from subscribing to seeing value in hours rather than weeks. Both efforts enable the curated solutions you already trust to deliver stronger outcomes together than they do apart.
That’s the build we’re accelerating with our partners now, and you’ll hear more leading into re:Invent.
If you’re running open source in production and don’t yet have supply chain visibility, start there. Activate Chainguard and Socket through the Security Hub console today. If you’re managing multiple security vendor relationships and want to understand what consolidation looks like with Security Hub Extended, talk to your AWS account team. Pricing for every partner is published on our pricing page, no sales call required. And if you’re already using Security Hub for posture management and threat detection, the Extended plan is available in the same console you already use.
We’re just getting started.
If you have feedback about this post, submit comments in the Comments section below.
Post Syndicated from Harish Ramesh original https://aws.amazon.com/blogs/big-data/fresher-insights-faster-decisions-talabats-near-real-time-analytics-across-aws-and-google-cloud/
talabat is the leading everyday app in the Middle East and North Africa (MENA) region, offering customers a convenient and personalized way to order food, groceries, and other everyday essentials from a wide selection of restaurants and retailers. Founded in Kuwait in 2004, talabat has expanded its operations to the United Arab Emirates, Oman, Qatar, Bahrain, Jordan, Iraq, and Egypt, serving over seven million monthly active customers as of December 2025. talabat is headquartered in Dubai, United Arab Emirates, and in December 2024 successfully completed its initial public offering on the Dubai Financial Market (DFM). As a subsidiary of Delivery Hero SE, talabat uses global expertise to continuously enhance its service, expand its landscape, and drive innovation. With a strong network of partners and riders, talabat connects customers to what they need, when they need it – powering everyday convenience across the region.
In this post, we show how talabat built a hybrid, multi-cloud lakehouse that keeps a single Apache Iceberg copy of streaming data on AWS while enabling governed, near-real-time analytics from Google Cloud Platform (GCP).
Data is the nervous system of talabat’s business. From the moment a customer hits “order” to the second their doorbell rings, talabat’s systems make split-second, data-driven decisions, instantaneously optimizing pricing, dispatch, routing, and order security. Over the years, talabat’s application grew into a landscape spanning two public clouds. Our transactional and operational backbone matured on AWS, where the engineering teams build and operate services. In parallel, a large population of analysts, data scientists, and analytics-engineering pipelines standardized on the Google Cloud Platform warehouse, Google BigQuery.
Both investments are deep, and both deliver value. So the strategic question wasn’t “which cloud do we consolidate on,” but rather “how do we make our data flow cleanly across the boundary between them.” That framing shaped everything that follows. The challenge isn’t only cross-cloud but cross-Region as well, with AWS services hosted in the EU region and the data in the GCP US region.
The following diagram shows how talabat’s data flows between the operational plane on AWS and the analytics plane on GCP.
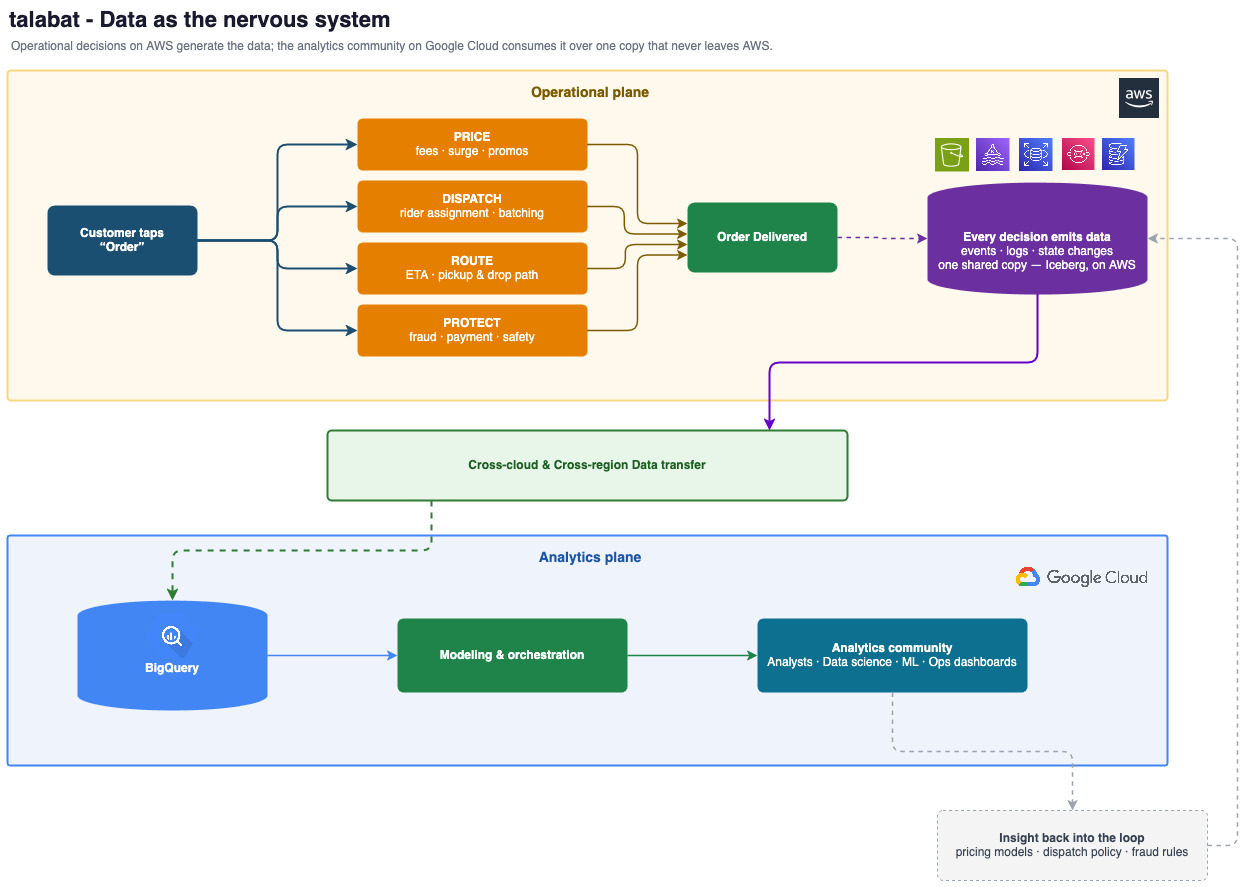
Figure 1: Data flow between the operational plane on AWS and the analytics plane on Google Cloud
Historically, the data engineering team orchestrated the data movement between the two clouds, mandating a physical movement from AWS to GCP, EU to US. Moving this using conventional extract, transform, and load (ETL) tools and frameworks delayed and duplicated the data through multiple hops: Amazon Relational Database Service (Amazon RDS) to Amazon Simple Storage Service (Amazon S3) EU AWS Region, Amazon S3 EU to Amazon S3 US Region, and finally Amazon S3 US to BigQuery US.
Each hop was a copy, and every copy compounded risk: multiple failure points, compounding latency, redundant compute and storage, type fidelity, and most importantly, cross-Region and cross-cloud egress cost.
In short, the old design paid in dollars, latency, and reliability to solve a problem it had created for itself: it moved data so that BigQuery could read it. A classic data warehouse bottleneck. Could we use an open data lake instead? Yes. But the analytics usage is heavy on BigQuery, which limits access through an open source data lake layer. So the redesign started from the opposite premise: keep one copy on AWS and let BigQuery read it in place. That is what the rest of this post describes: a lakehouse for talabat.
Operational systems emit a continuous stream of business events like order lifecycle changes, vendor, menu, logistics and rider signals, and payments information published to Apache Kafka on Amazon Managed Streaming for Apache Kafka (Amazon MSK). These events are encoded as Protocol Buffers and governed by backward-compatible schemas registered in Confluent Schema Registry, so producers and consumers can evolve safely over time.
The requirement on the analytics side is straightforward to state and hard to meet: make these events queryable, correctly typed, within minutes of being produced, and make them queryable from the tools each team already uses.
It’s tempting to view a two-cloud footprint as technical debt. For a real-time business like talabat, it’s simply the terrain, and each side plays to a genuine strength:
Consolidating either side would mean a multi-year migration and a significant regression in capability for one group of users, all to remove a seam between ingestion and analytics. Data engineers decided to engineer the seam instead. The design goal became a single sentence: keep one physical copy of the data on AWS, and read it natively from both clouds. A hybrid data lakehouse makes the “which cloud” question an access-path detail rather than an architectural fork.
Our first attempt inverted the flow we eventually shipped. Raw (also called Bronze) layer data was written from AWS directly into BigQuery-managed Iceberg tables on Google Cloud Storage. On paper, this placed the data closest to the largest consumer base. In practice, writing across clouds on an always-on streaming path introduced a class of problems we did not want to live with:
The lesson was clear: Shift left. The write path should be short, local, and straightforward. The cross-cloud concern belongs on the read path, where it can be made read-only, cached, and retried without affecting the ingestion. That reframing led directly to the architecture we run today.
With the flow inverted (raw data on AWS, read from Google Cloud), we evaluated three ways for BigQuery to read tables that physically live on AWS. We assessed each against four criteria:
| Approach | Assessment |
| Cross-cloud write to Google Cloud Storage | Continue writing bronze into BigQuery-managed Iceberg on Google Cloud Storage. We rejected this for the preceding reasons: it puts a cross-cloud dependency and cross-Region latency on the ingestion hot path. |
| BigQuery Omni | Query AWS resident data through the managed cross-cloud compute of BigQuery Omni. This introduced more managed surface and more constraints than we needed for a read-only bronze layer, and we wanted to own the catalog and trust model directly. |
| Lakehouse federated Apache Iceberg REST catalog (authenticated by IAM) | Let BigQuery read data in Amazon S3 Tables, a capability of Amazon S3 that provides managed Apache Iceberg tables, through a federated catalog that synchronizes AWS Glue Data Catalog metadata, with access authenticated by cross-cloud IAM trust. This met all four criteria, and we chose it. |
The deciding properties were that the raw data doesn’t leave AWS, the format is open Apache Iceberg (so Amazon Athena, Spark, and Iceberg-compatible engines read the same tables), and the cross-cloud relationship is expressed as identity and trust rather than as a recurring copy job.
With the architecture settled on a single Iceberg copy living on AWS, we needed a storage layer purpose-built for Iceberg at scale. Amazon S3 Tables met the requirements without adding operational surface. Table maintenance (compaction, snapshot expiration, and unreferenced file removal) runs automatically as a service-managed policy, avoiding the need for external orchestration jobs that would otherwise grow linearly with table count. Equally important, every table is an Amazon Resource Name (ARN)-addressable resource. That means IAM policies can grant or deny access for individual tables, the same least-privilege model we apply to any other AWS resource, and AWS CloudTrail records every access decision. For a cross-cloud design where the trust boundary is expressed entirely through IAM, having tables that are first-class IAM resources isn’t a convenience but a prerequisite. S3 Tables gave us managed Iceberg housekeeping and fine-grained, auditable access control in a single construct, so the engineering team could focus on the streaming logic rather than the storage plumbing beneath it.
The system has two halves that meet at an open table format:
The single source of truth is Apache Iceberg data in Amazon S3 Tables. Every consumer reads that one physical copy.
The following diagram shows the end-to-end architecture, from event ingestion through storage to consumption paths.
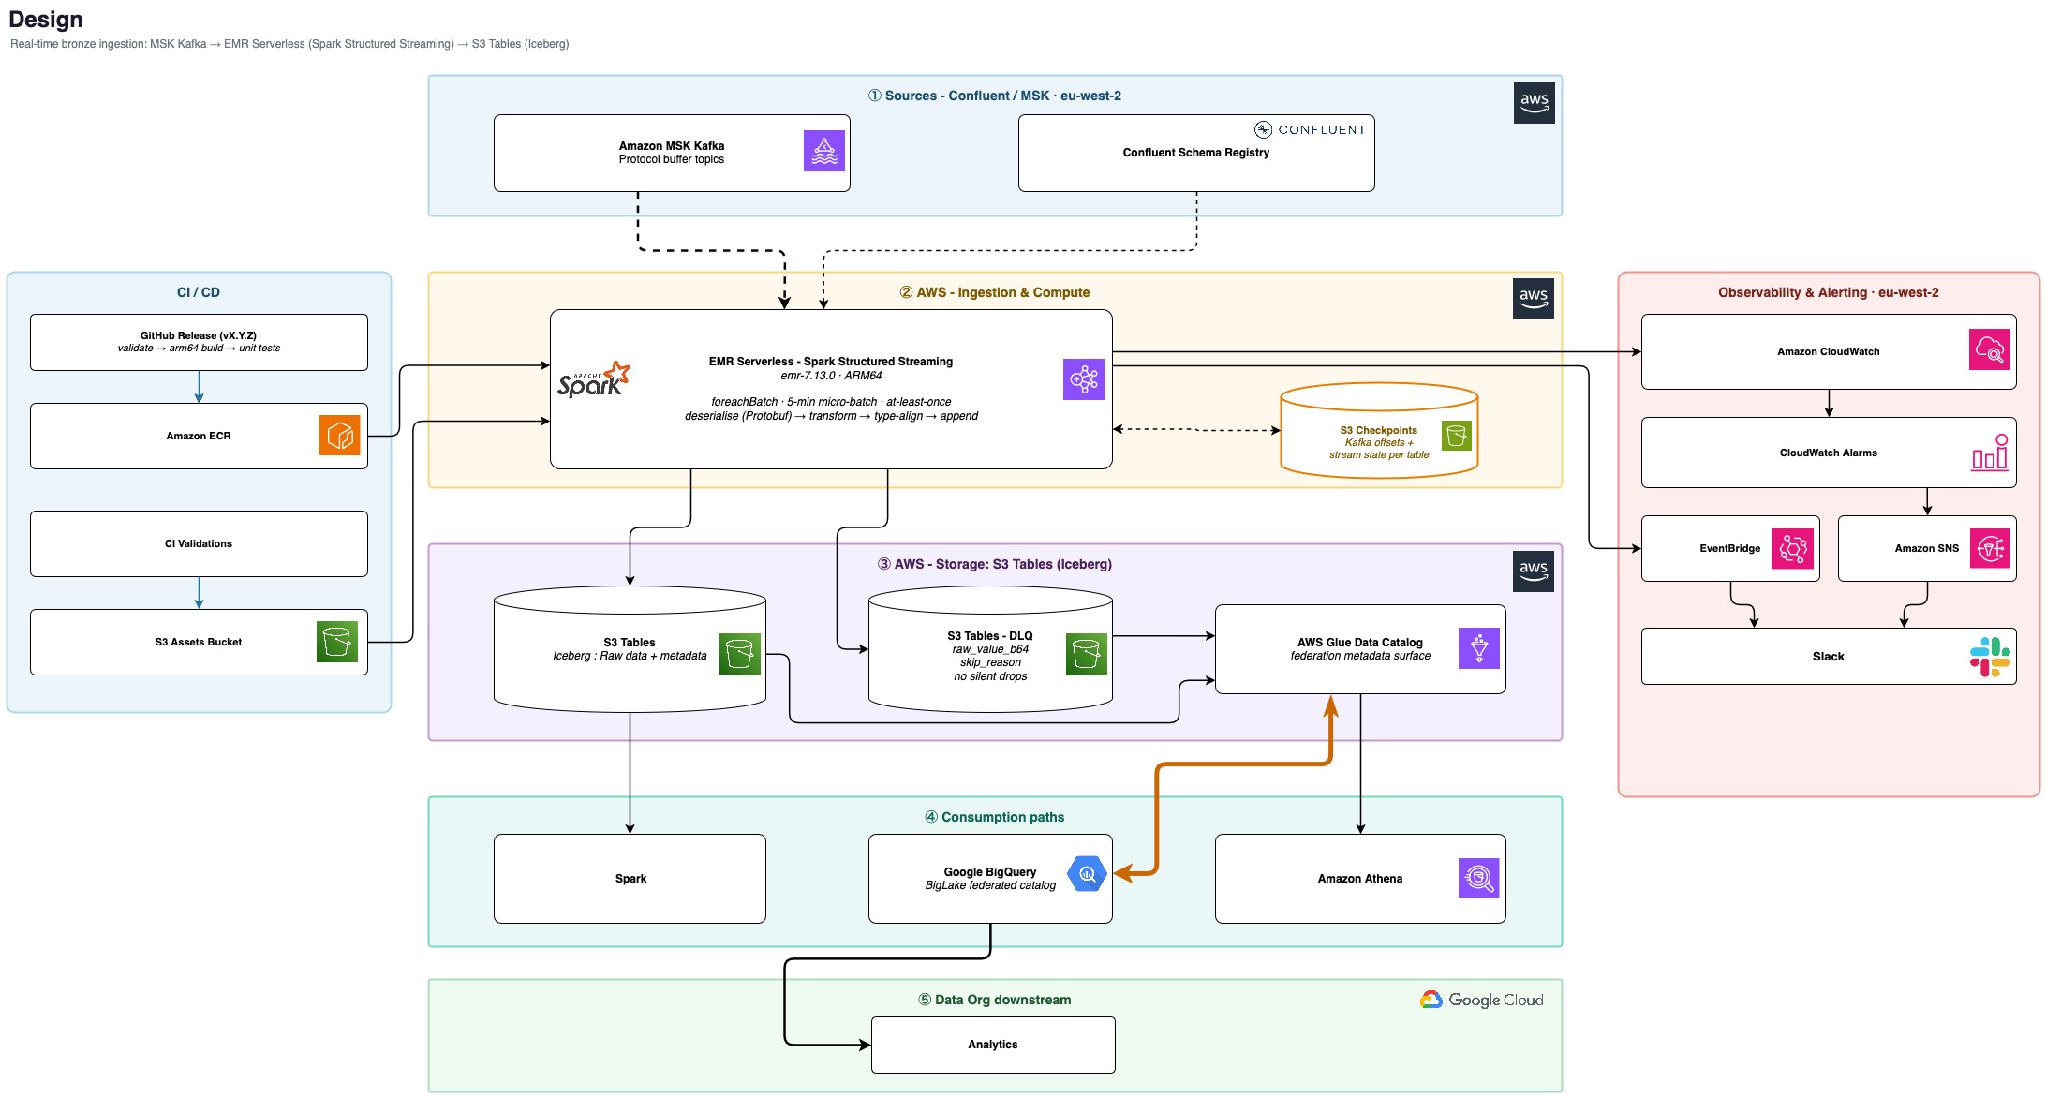
Figure 2: End-to-end architecture from event ingestion through storage to consumption paths
We run one Amazon EMR Serverless Spark Structured Streaming job per Kafka topic (with a prebaked Docker image, emr-7.13.0 on ARM64/Graviton) in the same AWS Region (eu-west-2) as Amazon MSK. Co-locating compute with the event backbone minimizes the data transferred per micro-batch, saving cost and latency. Each job runs the Spark foreachBatch operation with a trigger interval of roughly one to five minutes and at-least-once delivery. Every micro-batch performs five steps:
The cycle repeats without interruption.
This path touches only AWS. There is no cross-cloud dependency, only one deliberate cross-Region hop: compute in the Europe (London) Region (eu-west-2), storage in the US East (N. Virginia) Region (us-east-1). This incurs standard AWS inter-Region data transfer cost, a deliberate choice so that the cross-cloud read from BigQuery stays within the same Region.
Bad records don’t block the stream. They land in a dedicated dead-letter queue (DLQ) table (<table>_dlq) in a separate S3 Tables bucket, storing the raw payload (raw_value_b64) and a skip_reason. Nothing is silently dropped. The DLQ tables are registered with the AWS Glue Data Catalog through Lakehouse, so engineers can inspect failures from Amazon Athena or BigQuery.
From this point on, Amazon S3 Tables is the source of truth.
This is the heart of the design. BigQuery reads the S3 Tables Iceberg data through a Lakehouse federated Apache Iceberg REST catalog, a read-only catalog on the Google Cloud side that points at the AWS resident tables. Three mechanisms make it work.
Amazon S3 Tables exposes an Apache Iceberg REST catalog interface, and Google Lakehouse speaks that same standard. Because both sides agree on the Iceberg on-disk format and REST catalog protocol, no translation layer or data copy is required. BigQuery reads the identical Iceberg data files that Athena and Spark read.
On the Google Cloud side this is a single Lakehouse federated catalog. A table surfaces to analysts as
talabat-data.s3tables-glue.catalog.orders.
The Lakehouse catalog authenticates to AWS as a Google-managed service identity (the Lakehouse REST-catalog service account) that an AWS Identity and Access Management (IAM) role trusts through OpenID Connect (OIDC) federation with
accounts.google.com, usingsts:AssumeRoleWithWebIdentitywith the service account’s numeric ID pinned in the role’s trust policy. Requests to the S3 Tables Iceberg endpoint are SigV4-signed. It’s the same AWS request-signing scheme that any AWS SDK uses, scoped to the S3 Tables service. In other words, the handshake isn’t a proprietary connector. It’s standard AWS request signing performed by a trusted external identity.The trust is codified as infrastructure as code (IaC) on the AWS side: granted least-privilege, and revocable at any time. The following diagram shows this authentication sequence.

Figure 3: Cross-cloud authentication sequence between the Lakehouse catalog and AWS IAM
For a step-by-step walkthrough of this trust relationship, creating the IAM role, validating the token’s audience and subject, and pinning the Lakehouse service-account identity in the trust policy, see Create and manage AWS Glue federated datasets and Set up cross-cloud Lakehouse for AWS Glue.
The federated catalog periodically synchronizes table metadata from the AWS Glue Data Catalog that fronts S3 Tables. Newly created tables and new data become visible to BigQuery on a short refresh cycle (approximately 300 seconds). Reads are served against the live Iceberg data. Only the catalog pointers are synchronized.
The result is that a table written once on AWS appears in BigQuery as an ordinary catalog object and can be queried with standard SQL, while the bytes don’t leave AWS and the format stays open.
The following section explains the authentication handshake shown in the architecture diagram. The Lakehouse catalog service account presents a Google OIDC JSON Web Token (JWT), which AWS validates through the IAM OIDC provider, returning short-lived credentials scoped to read-only S3 Tables access.
Together these four steps are the whole handshake: a trusted issuer, a role that only our service account can assume, a least-privilege read grant, and a catalog bound to that role.
Operating an open, federated catalog across clouds taught us to treat table metadata as a first-class operational concern. In practice this means:
These are small, well-understood settings once we know how to set them, and they are the difference between a catalog that simply works and one that drifts.
After a source is live, the same Iceberg table is available three ways over one physical dataset.
Nobody waits for a nightly export, and nobody reconciles three divergent copies. There is only one.
The qualitative benefits are already clear:
Looking ahead, we plan to broaden source coverage by onboarding the remaining high-value event streams and batch stores onto a hybrid one-configuration pattern. We’re formalizing end-to-end freshness objectives and the observability around them: batch-level metrics, dead-letter monitoring, and catalog-synchronization health. We will continue tuning snapshot retention and compaction so the cross-cloud catalog stays fast and reliable as the number of tables grows. More broadly, we intend to make “written once, read by any engine” the default for new datasets beyond the bronze layer, leaning further into open table formats as the connective tissue between cloud service providers.
Being on two clouds is often framed as a problem to migrate away from. It’s simply the terrain for talabat. The event backbone is prominent on AWS, and the analytics community operates on BigQuery. By making Amazon S3 Tables with Apache Iceberg the single source of truth on AWS and letting BigQuery consume it read-only through a Lakehouse federated Iceberg REST catalog secured by cross-cloud IAM trust, we turned a two-cloud constraint into a single governed dataset that engines can read within minutes. The write path stays short, local, and reliable. The cross-cloud concern lives on the read path, where it belongs, expressed as open standards and identity, not as data movement.
That is the handshake: one copy of the data on AWS, an open catalog contract, and a signed, trusted, revocable identity reaching across the cloud boundary to read it.
This post focuses on reading AWS resident data from BigQuery. For the broader multi-cloud Lakehouse pattern, including federating catalogs from other systems into the AWS Glue Data Catalog, see Multi-cloud Lakehouse architecture on AWS for agentic AI.
Post Syndicated from Mazrim Mehrtens original https://aws.amazon.com/blogs/big-data/powering-agentic-ai-with-real-time-streaming-data-on-aws/
Two years ago, the conversation about streaming data and generative AI centered on a straightforward question: how do you feed real-time context into a large language model (LLM) so it can answer questions using fresh data? We explored that question in our 2024 blog post, “Exploring real-time streaming for generative AI applications,” which introduced patterns for connecting streaming pipelines to foundation models.
The landscape has shifted. Today’s generative AI systems don’t only answer questions. They observe, reason, and act. Agentic AI applications have moved from research prototype to production reality. Agentic AI-powered data pipelines now monitor streaming telemetry, detect anomalies, decide on remediation strategies, and execute actions without human intervention. They maintain memory across sessions, query live data sources on demand, and coordinate with other agents to solve complex problems.
This shift demands a fundamentally different relationship between streaming infrastructure and AI. It’s no longer enough to inject context into a prompt. You need architectures where streaming data continuously powers autonomous agent action and keeps a real-time lakehouse fresh for training and retrieval. That data also flows into multiple consumption patterns, such as generative business intelligence (BI) for humans, standardized protocols for agent queries, and proactive memory hydration for low-latency agent context.
This post introduces three architectural patterns that together form a unified streaming backbone for the agentic AI era:
The following sections explore each pattern in depth.
You’re watching a live football match. As a striker receives the ball in the box, AI-generated commentary appears on screen: “This is Smith’s third touch in the penalty area in the last 3 minutes. His conversion rate from this zone is 34% this season.” That insight was computed from streaming event data, passed through a feature pipeline, and fed to a generative AI model. All of this happened within the time it takes the striker to turn and shoot.
This pattern combines two capabilities that are often treated separately: using real-time data to continuously improve AI models, and using real-time data to invoke those models for immediate action. The streaming pipeline does both: it builds the features that train the model and the features that drive inference.
Streaming events (user interactions, sensor readings, game events, and transaction records) flow into Amazon Managed Streaming for Apache Kafka (Amazon MSK) or Amazon Kinesis Data Streams. Amazon Managed Service for Apache Flink processes these events through windowed aggregations (tumbling windows, sliding windows, or session windows) to produce features: rolling averages, counts, ratios, behavioral sequences, or other derived signals relevant to your use case.
These features serve two paths simultaneously:
The inference path: At the end of each window (or on each event, depending on your latency requirements), features are passed to a generative AI or machine learning (ML) inference endpoint: Amazon Bedrock for generative output, or Amazon SageMaker for custom models. The model produces a result (commentary, a recommendation, a personalization decision, or a risk score) and the pipeline acts: posting content to a user, updating a recommendation feed, sending a notification, or writing to a downstream system.
The training path: The same streaming features are continuously written to a real-time data warehouse or lakehouse such as Apache Iceberg tables on Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3), that keeps training datasets fresh. Amazon SageMaker lakehouse architecture provides unified access for training jobs and fine-tuning pipelines. As new data streams in, your models can be retrained or fine-tuned on data that’s minutes old rather than days old. This matters for domains where patterns shift quickly, such as fraud detection, personalization, and industry dynamics.
Amazon S3 Tables handles the Iceberg table management automatically, including compaction, snapshot management, and metadata optimization. Your team focuses on feature logic rather than storage operations. The AWS Glue Data Catalog makes these tables discoverable across training jobs, inference pipelines, and analytics consumers. Glue Data Catalog supports business context and semantic search. This context helps models discover and select the right data asset for any given task.
Real-time sports commentary: Streaming game events (passes, shots, player positions) flow through Apache Flink on Managed Service for Apache Flink, which computes rolling features (possession percentage, shot frequency by zone, player heat maps). These features feed a generative AI model through Amazon Bedrock that produces natural-language commentary and statistical insights in real time. Simultaneously, the features are written to S3 Tables to improve the model’s understanding of game patterns over time.
Streaming personalization: User clickstream data flows through Managed Service for Apache Flink, which computes behavioral features (session duration, category affinity scores, recency-weighted purchase history). These features invoke a personalization model that updates the user’s experience in real time by reranking product recommendations, adjusting content feeds, or triggering targeted offers. The same features feed the lakehouse to retrain the personalization model nightly.
Figure 1: Streaming feature engineering feeding a real-time inference path and a continuous training path
At 2:47 AM, a pressure sensor on a manufacturing line begins drifting. Within seconds, a streaming pipeline detects the anomaly, assembles full context (device history, maintenance schedule, correlated sensor readings), and invokes an agent that opens a maintenance work order, adjusts the device’s sampling rate, and notifies the on-call engineer. All of this happens before a human sees an alert.
Pattern 1 invokes inference on every window or event. It runs continuously. Pattern 2 adds to this approach: the streaming pipeline continuously analyzes data and invokes an agentic workflow when specific conditions are met or a pattern is detected. The pipeline is the sensor. The agent is the responder. Dynamic rules are the bridge between them.
The key distinction is that the events and triggers are dynamic. They’re defined by rules programmed into the streaming pipeline or traditional ML models for prediction or detection. The pipeline determines when and how the agent is triggered, making the system fluid and adaptive. You can update detection logic without redeploying the agent. You can add new anomaly patterns without changing the response logic.
Streaming telemetry flows into Amazon MSK or Amazon Kinesis Data Streams. Managed Service for Apache Flink runs continuous anomaly-detection logic, such as statistical models, windowed aggregations, threshold-based rules, or ML-based scoring. Critically, when Flink detects an anomaly, it doesn’t only publish a raw alert. It assembles a context package: the anomaly details, relevant historical data, correlated signals from other streams, and metadata the agent needs to act immediately.
This context package is published to a downstream topic and consumed by an Amazon Bedrock AgentCore agent. Because the pipeline has already assembled full context, the agent doesn’t waste time gathering information. It can reason and act immediately. AgentCore Runtime hosts the agent, AgentCore Observability provides tracing and logging, and AgentCore Memory maintains state across invocations (so the agent knows, for example, that this is the third anomaly from this device this week).
The benefit of this pattern over a polling-based or scheduled approach is twofold:
The rules that trigger invocation are a powerful abstraction. They can be simple thresholds (“temperature exceeds 95°C”), statistical (“value deviates more than 3σ from the rolling mean”), or ML-based (“anomaly score from an embedded model exceeds 0.85”). You can update these rules dynamically by adding new detection patterns, adjusting sensitivity, or routing different anomaly types to different agents.
Figure 2: Event-driven agent invocation triggered by anomaly detection in the streaming pipeline
A customer messages their bank: “Was that $847 charge at the airport legitimate?” The agent responds in under two seconds with full context (the customer’s recent travel pattern, the merchant’s fraud-risk score, and the transaction details) because all of this was already loaded into the agent’s context layer through streaming CDC. A reactive agent without this synchronization would need to make five separate API calls across three systems, taking 8–12 seconds and risking timeout failures.
This pattern addresses a fundamental question: how proactive should your agent be about gathering context?
A proactive agent has the full context, continuously synchronized with the state of the world. When a user asks a question, the agent already has the relevant knowledge from context. It responds from memory rather than making expensive external calls. A reactive agent starts cold. It knows nothing until it queries for information, making multiple calls across security boundaries, handling authentication, and stitching together data from disparate sources. For latency-sensitive use cases, where a user sends a prompt and expects a fast response, this difference is critical.
Real-time context synchronization uses CDC and streaming pipelines to keep agent memory current. The agent’s knowledge graph becomes a synchronized replica of the distributed systems it needs to reason about.
No agent is purely proactive or purely reactive. The design decision is: what data should be pre-loaded, and what should be fetched on demand? This is a spectrum, and where you land depends on three factors:
Streaming pipelines (Managed Flink reading from Amazon MSK, Kinesis Data Streams, or CDC streams from operational databases) continuously process events and write aggregated results to the agent’s knowledge graph, or the context layer. These stores can take multiple forms depending on your access patterns:
For data that isn’t pre-loaded, the agent falls back to on-demand retrieval. This applies when the data is too large, changes too rarely to justify streaming, or is needed only in edge cases. The Model Context Protocol (MCP) provides a standardized interface for this. MCP servers expose heterogeneous data sources through a uniform protocol. The agent queries MCP when it needs context that isn’t in its synchronized memory.
This same real-time context synchronization pattern serves different consumers:
AI agents access fresh context through a real-time knowledge graph or a context layer, and MCP servers (pull tier), as in the preceding sections.
Human analysts and executives access the same context layer, which can directly query Apache Iceberg tables on S3 Tables through its direct query mode. Amazon Quick chat provides natural-language access to real-time lakehouse data. No intermediate warehouse is required. This is the generative BI expression of the same underlying pattern: streaming data keeps the lakehouse current, and Amazon Quick gives humans conversational access to it.
Training and fine-tuning pipelines access the synchronized lakehouse through Amazon SageMaker Lakehouse, keeping models fresh (as described in Pattern 1).
The underlying principle is the same across consumers: streaming pipelines synchronize distributed data into accessible stores, and each consumer accesses those stores through the interface that fits their needs.
Figure 3: Real-time context synchronization serving agents, analysts, and training pipelines from shared stores
The three patterns in this post form a unified architecture built on a single streaming backbone:
Pattern 1 uses streaming pipelines to build features that simultaneously drive real-time inference and keep training data fresh. Your models improve continuously while serving predictions in real time.
Pattern 2 uses streaming pipelines as intelligent sensors that detect anomalies and invoke agents with full context already assembled. This separates detection logic from response logic for maximum flexibility.
Pattern 3 uses streaming pipelines to synchronize distributed system state into the agent’s context layer, making agents more proactive and serving multiple consumers (agents, humans, and training jobs) from the same pre-loaded data.
The streaming infrastructure you build (Amazon MSK, Amazon Kinesis Data Streams, Amazon Managed Service for Apache Flink, and Amazon S3 Tables) serves all three patterns simultaneously. A Flink application can compute features for inference (Pattern 1), detect anomalies that trigger agents (Pattern 2), and synchronize state into agent memory (Pattern 3).
To get hands on with the patterns described in this post, refer to Agentic AI-Powered anomaly detection: Spotting anomalies in real-time.
You don’t need to implement all three patterns at once. Start with the one that addresses your most pressing need. But design your streaming infrastructure knowing it will serve multiple patterns. In the agentic AI era, every stream is a potential input to an agent, a model, and a human decision-maker.
Post Syndicated from Rommel Sunga original https://aws.amazon.com/blogs/messaging-and-targeting/send-rich-rcs-messages-with-aws-end-user-messaging-rcs/
When a customer asks where their order is, a plain text reply answers the question. But a rich RCS message with a product photo, a tappable confirmation button, and a calendar chip helps the customer act on it. Rich Communication Services (RCS) messages deliver branded, interactive content, including images, rich cards, carousels, and suggestion chips, to the messaging app already built into the customer’s phone. Unlike Short Message Service (SMS), RCS messages come from a verified sender with your brand name and logo, deliver over a data connection, and support read receipts and structured replies. AWS End User Messaging RCS provides the SendRcsMessage API, a managed way to send RCS messages through a single integration point instead of separate integrations for each carrier.
This post is for developers and solutions architects who want to add RCS messaging to their customer engagement workflows on AWS. It shows how to send every RCS content type (text, files, rich cards, carousels, and suggestions). It also shows how to control delivery with message expiration and SMS fallback, using Python and the AWS End User Messaging RCS API.
The post focuses on the SendRcsMessage API, which is specific to RCS and is the only one of the two that supports rich cards, carousels, and suggestions. The SMS API’s SendTextMessage can also deliver over RCS when you pass an RCS agent as the origination identity, but it is limited to plain text. Every example that follows uses SendRcsMessage.
Before you run the examples in this post, you need the following:
VERIFIED.SendRcsMessage support. Run pip install --upgrade boto3 to get the latest version.If you’re new to RCS on AWS, see Getting started with RCS on AWS End User Messaging SMS to create your agent. You pay standard RCS rates for RCS messages, including messages sent to test devices.
The AWS Identity and Access Management (IAM) principal that runs the examples needs permissions for the following actions:
sms-voice:SendRcsMessage, to send RCS message types.sms-voice:SendTextMessage, to send the plain text comparison example and any SMS fallback messages.sms-voice:DescribeRcsAgents, to check that your agent is Active.sms-voice:DescribeVerifiedDestinationNumbers, to confirm a registered test device is VERIFIED, if you send to one.If you use the SMS fallback example, you also need a phone number or sender ID in your account that can send SMS to the destination country. RCS and SMS are separate origination identities: the RCS agent sends the RCS message, and the fallback needs its own SMS-capable identity.
If you send media from Amazon Simple Storage Service (Amazon S3), the bucket needs a resource policy granting the sms-voice.amazonaws.com service principal s3:GetObject, shown in the “File messages” section. If you use server-side encryption with AWS Key Management Service (AWS KMS) keys for your bucket, your KMS key policy must also grant the service access. For two-way messaging, your SNS topic needs a resource policy allowing the service to publish to it. For details, see Two-way messaging in the AWS End User Messaging SMS User Guide.
Create a config.json file in your project directory to store the RCS agent Amazon Resource Name (ARN) that sends the messages and the recipient phone number in E.164 format:
OriginationIdentity accepts the RCS agent ID (RcsAgentId) or ARN (RcsAgentArn), and also a pool ID or pool ARN. The examples use the agent ARN because it stays unambiguous when an account has more than one agent, but the shorter agent ID works the same way.
The config.json file is for local testing only. In production, don’t hardcode phone numbers and identifiers. Use AWS Secrets Manager, AWS Systems Manager Parameter Store, or environment variables instead.
Each example in this post builds a message_content dictionary and sends it with the following code:
For production use, wrap the send call with error handling to manage throttling and validation failures:
The following sections show only the message_content for each message type. To send any of these messages, use the shared sending code from this section. The examples follow one scenario: AnyCompany, a fictitious retailer, messaging a customer about an order.
Text messages are the most basic RCS content type. You can send plain text two ways. The SendTextMessage API, the same API used for SMS, delivers over RCS when you pass your RCS agent ARN as the origination identity:
The SendRcsMessage API sends the same text as a TextMessage content type, and additionally supports suggestion chips, message expiration, and per-message fallback. An RCS text also arrives as a single message regardless of length, while carriers split SMS over 160 characters into segments that can arrive out of order.
FallbackConfiguration, recipients who can’t receive RCS get nothing.
Figure 1: RCS text message confirming that order ORD-2026-001 has shipped
The following is the message_content for the preceding message:
With file messages, you send a single image, video, audio file, or PDF that renders as inline media in the recipient’s messaging app. FileUrl accepts two URL forms, and they fail in different places.
With an S3 URL (s3://amzn-s3-demo-bucket/object-key), the API checks at request time that the object exists, is within the size limit, and is readable with the permissions you granted the service. If any of those checks fail, the call returns a ValidationException describing the problem, so you find out at send time. The service then retrieves the object, rehosts it, and generates a time-limited presigned URL for delivery to the device.
With an HTTPS URL, the URL is passed through to the carrier and isn’t checked the same way at request time. The API accepts the request. Problems such as an unreachable host, a URL that requires authentication, or an unsupported media type surface at delivery instead of in the API response. The URL must be publicly accessible with no authentication. The API doesn’t support plain http:// URLs.
Use S3 URLs when you want bad media to fail loudly at send time. Use HTTPS URLs for media already published on a public CDN, and monitor delivery events for failures.
FileUrl: required, S3 or HTTPS URL, up to 2,000 characters.ThumbnailUrl: optional, JPEG or PNG, recommended for video and PDF.To deliver from Amazon S3, add the following bucket policy so the service can read your objects:
Replace amzn-s3-demo-bucket with your bucket name. To restrict access to a prefix, replace /* in the Resource ARN with a path such as arn:aws:s3:::YOUR-BUCKET/rcs-media/*.
Figure 2: RCS file message rendering an inline PDF attachment
The following is the message_content for the preceding message:
A rich card combines media, a title, a description, and suggested actions into a single structured message. Rich cards work well for product highlights, booking confirmations, appointment details, and promotional offers.
CardContent requires at least one of Media, Title, or DescriptionCardOrientation is required: VERTICAL or HORIZONTAL. Use VERTICAL because horizontal orientation truncates images on iOS.Media Height: SHORT (112 density-independent pixels), MEDIUM (168), or TALL (264). IOS ignores this value.OpenUrl suggestions for links.
Figure 3: Vertical rich card with a product image, title, description, and action buttons
The following is the message_content for the preceding message:
A carousel displays 2–10 rich cards in a horizontally scrollable strip. Carousels fit browse-and-compare experiences such as product catalogs, service menus, plan comparisons, and location listings. Carousel cards use the same content model as standalone rich cards, with two differences: cards always render in a vertical layout, and the TALL media height is not supported.
CardWidth: SMALL (180 density-independent pixels) or MEDIUM (296). All cards share the same width.Media Height: SHORT or MEDIUM only.
Figure 4: Carousel showing the Wireless Headphones and Smart Watch cards, each with a Select button
Scrolling right reveals the remaining cards:
Figure 5: Carousel scrolled to the Portable Speaker card
The following is the message_content for the preceding message:
Suggestions are the interactive chips you saw in the earlier examples. They guide recipients through a conversation with predefined replies and actions, without typing. RCS supports six suggestion types: Reply, OpenUrl, DialPhone, ShowLocation, RequestLocation, and CreateCalendarEvent, and you can mix them in one message on any content type. Message-level suggestions live in a Suggestions array that is a sibling of Content, not nested inside it. Card-level suggestions live inside each card’s CardContent.
Every suggestion requires a Text label and PostbackData. The postback data is invisible to the recipient and comes back to your application when the chip is tapped. Encode routing information there (for example, appt_confirm_12345), and route logic on postback data rather than display text.
Text label: up to 25 characters; PostbackData: up to 2,048 characters, both required on every suggestion.OpenUrl Url must begin with https://. Set Application to WEBVIEW with a WebviewViewMode of FULL, HALF, or TALL to keep the recipient inside the messaging app.DialPhone PhoneNumber must be in E.164 format.CreateCalendarEvent requires Title, StartTime, and EndTime
Figure 6: RCS message confirming a fitting appointment at AnyCompany Anytown
Figure 7: Suggestion chips below the appointment message: Confirm, Reschedule, Manage booking, and Call the store
Scrolling the chip row reveals the remaining suggestions:
Figure 8: Remaining suggestion chips: View store map, Share my location, and Add to calendar
The following message_content combines all six suggestion types on one text message:
When the recipient taps a chip, the messaging app sends the chip text back into the conversation as a reply:
Figure 9: Tapping Confirm sends the chip text back as a reply, shown with a read receipt
The tap arrives as an inbound event on your two-way SNS topic. The messageBody field contains a JSON string with a type of SUGGESTION, the display text, and the postback data:
Note the casing difference: request fields use PascalCase (PostbackData), while inbound events use camelCase (postbackData). A RequestLocation tap delivers the recipient’s coordinates in a separate inbound location event.
The TimeToLive parameter sets an expiration window in seconds on a SendRcsMessage request. If the message is not delivered within that window, the service removes it and the recipient never sees it. This matters for time-sensitive content such as one-time passwords (OTPs): a verification code that arrives after the code has expired only confuses the customer.
TimeToLive: integer seconds, 1–172,800 (48 hours). Use at least 10 seconds so the carrier can attempt delivery.TimeToLive means no expiration window.TTL_EXPIRATION_REVOKED event (message removed, safe to send a fallback) or TTL_EXPIRATION_REVOKE_FAILED (revoke failed, the message might still deliver, so weigh the duplicate risk)
Figure 10: RCS verification code delivered within its five-minute expiration window
The following example sends an OTP that expires after five minutes. TimeToLive is a request parameter, a sibling of RcsMessageContent:
Fallback is optional, and without it a recipient who can’t receive RCS gets nothing. The FallbackConfiguration request parameter routes the message to SMS or Multimedia Messaging Service (MMS). Fallback applies when the device or carrier doesn’t support RCS, when the channel rejects the message, or when the TimeToLive window expires first.
Channel: required, SMS or MMS.MessageBody: required for SMS fallback, up to 1,600 characters (compared with 3,072 for the RCS text body); MMS fallback requires at least one of MessageBody or MediaUrlsOriginationIdentity for the fallback: a phone number or sender ID registered in your account that can send SMS or MMS to the destination country. Pools and RCS agents are not accepted here.
Figure 11: AnyCompany delivery notification delivered over RCS
On a device without RCS, the SMS fallback version arrives instead from the fallback phone number.
The following example sends a delivery notification with an SMS fallback from a dedicated phone number:
To track outcomes, pass ConfigurationSetName on the send call so delivery, read, expiration, and fallback events route to your configuration set’s event destinations. Set up event destinations before you send, because they don’t retroactively capture events.
To avoid incurring future charges, delete the resources that you created during this walkthrough:
In this post, you learned how to send every RCS content type with AWS End User Messaging RCS, including text messages, file messages, rich cards, carousels, and suggestions. You also learned how to control delivery with message expiration and per-message SMS fallback. You sent each type from a short Python script, with one shared sending pattern across all content types.
The SendRcsMessage API keeps one pattern across all content types: a Content object for the message body and a sibling Suggestions array for interactivity. Moving from a plain text notification to a full product carousel is a change to one dictionary.
Next steps:
TimeToLive values with per-message SMS or MMS fallback for each use case.Create your first RCS agent in the AWS End User Messaging SMS & RCS console and send a test message today. Tell us about your experience: share your use cases and questions in the comments.
Post Syndicated from Ali Alemi original https://aws.amazon.com/blogs/big-data/amazon-msk-simplifies-configuring-custom-domain-names/
Previously, you had to manually override the advertised listener on each broker and repeat it every time a broker was added. This approach was operationally heavy and could not be implemented on a cluster in KRaft mode. With Amazon Managed Streaming for Apache Kafka (Amazon MSK), you can now configure custom domain names for your Provisioned clusters using a single property. This works for clusters in both ZooKeeper and KRaft mode. Now you define the domain once and Amazon MSK applies it across every broker, so custom domain names keep working through scaling of the MSK cluster.
Amazon MSK is a fully managed service for building and running applications that use Apache Kafka to process streaming data. By default, Amazon MSK brokers advertise addresses that AWS generates (for example, b-1.cluster-name.kafka.us-east-1.amazonaws.com) to connecting clients. These addresses are unique to each cluster and change when a cluster is recreated.
Many organizations need a static, customer-controlled endpoint that stays the same regardless of the underlying cluster. They achieve this with a custom domain name, so that they can:
Until now, the only way to do this was to override the advertised.listeners on each broker using the kafka-configs.sh --alter tool. It required carefully preserving every internal listener and re-running that override every time a broker was added. This works, but it accepts any string with no validation. A single typo can cause an outage. It requires manual, per-broker steps with no cluster-wide mechanism. It cannot be managed through infrastructure as code, and it could not be implemented on Amazon MSK brokers in KRaft mode. This blocked customers who rely on custom domain names from using them on KRaft-based clusters. With this launch, a single configuration property replaces all of that.
A working custom domain name has two parts, and understanding this split up front helps the rest of this post make sense. You own the client connectivity and trust layer. Amazon MSK owns the cluster-side advertised listener configuration. The following diagram shows the client connectivity and trust layer.
Figure 1: The client connectivity and trust layer (left) is a prerequisite you own and manage. The advertised listener configuration on the cluster (right) is what Amazon MSK manages for you
Important: When you apply
custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.
The Prerequisites section below shows the key requirements. You can find the detailed setup in an existing post, Configure a custom domain name for your Amazon MSK cluster, which includes a diagrammed walkthrough of the NLB, Amazon Route 53, and AWS Certificate Manager (ACM) topology.
After the connectivity layer exists, you tell the brokers which custom address to advertise to clients. This is the part that used to require a per-broker CLI override, and it is what this launch simplifies. This next section describes how it works.
Before a client can reach your brokers through a custom domain, the connectivity and trust path must exist. You create and manage this layer. It covers three things:
This layer must be in place for custom domain names to function. It is a prerequisite for this feature to work.
You add a property to your Amazon MSK configuration. The value takes the form:
where <LISTENER> is one of your cluster’s client listeners and <hostname>:<port> is the custom address pattern. For example, on an IAM cluster:
The property specifies two things:
CLIENT, CLIENT_SECURE, CLIENT_SECURE_PUBLIC, CLIENT_SASL_SCRAM, CLIENT_SASL_SCRAM_PUBLIC, CLIENT_IAM, and CLIENT_IAM_PUBLIC. Internal listeners (REPLICATION, CONTROLLER) are not supported and are rejected at validation. The listener you specify must also be bound (active) on your cluster. For example, if your cluster uses only IAM authentication, specifying CLIENT_SECURE is rejected, and the error message lists the valid client listeners for your cluster.hostname:port pattern that includes the {broker_id} template variable. Each broker resolves to a unique address. In this pattern, the {broker_id} template variable is replaced with each broker’s numeric ID. The port number 9000+{broker_id} means the broker ID is added to the base port 9000, so broker 1 resolves to 9001, broker 2 to 9002, broker 10 to 9010, and so on. The base port 9000 is only an example. You can use any base port, as long as the resulting ports match the TLS listeners you provisioned on your NLB.
{broker_id}can appear in the hostname, the port, or both, as long as each broker’s resolvedhost:portis unique. Placing it in the port alone is valid, so a shared hostname with a per-broker port also works:
Before you begin, you need an MSK configuration to hold this property. You create one with the CreateConfiguration API (or the AWS Management Console), passing your server properties as the configuration body. MSK returns a configuration ARN and a revision number, which together identify the exact configuration you apply to the cluster.
custom.advertised.listeners does not need its own standalone configuration. You can include it alongside any other broker-level properties MSK already supports, such as auto.create.topics.enable, num.partitions, or log-retention settings, within a single configuration revision. If you already manage an MSK configuration for your cluster, add custom.advertised.listeners to it and create a new revision using the UpdateConfiguration API. No separate configuration is needed.
You then apply the configuration to your cluster with the UpdateClusterConfiguration API. Amazon MSK then performs three actions:
These safeguards prevent you from accidentally removing or modifying the internal listeners that Amazon MSK manages. Validation is synchronous. The listener must be a client-facing listener, the pattern must include {broker_id}, and each broker’s resolved host:port must be unique. If any check fails, the API returns a descriptive error and makes no change.
The override affects only the advertised address of the named listener. Replication, authentication, multi-VPC (CLIENT_IAM_VPCE), and AWS PrivateLink connectivity remain unaffected. The change is also fully reversible: remove the custom.advertised.listeners property and re-apply the configuration, and Amazon MSK reverts the listener to its original address.
You can track progress with the DescribeOperation API, which shows state transitions from UPDATE_IN_PROGRESS to UPDATE_COMPLETE or UPDATE_FAILED. If a broker fails to start, the rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the property and re-apply to recover.
When you apply custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.
The networking layer, the Network Load Balancer (NLB), DNS, and TLS certificate that route traffic from your custom domain to your broker IPs, is a prerequisite you own. It is not specific to this launch. The existing post Configure a custom domain name for your Amazon MSK cluster covers it in detail, with a diagrammed walkthrough of the NLB, Route 53, and ACM topology. With the networking in place, the following steps cover the cluster-side setup this launch introduces.
Create or update an Amazon MSK configuration that includes the custom.advertised.listeners property, matching the hostnames and ports you provisioned on the NLB. For a three-broker IAM cluster fronted by an NLB with ports 9001–9003, put the property in a file:
Then create the configuration, passing the file as the server properties:
Use fileb:// (not file://) so the CLI reads the file as bytes and base64-encodes it. Passing the value inline is fragile because of the {broker_id} braces. Leave {broker_id} literal in the file. Amazon MSK resolves it per broker at apply time. The response returns the configuration ARN and LatestRevision.Revision, which you use in the next step.
Apply the configuration to your cluster with UpdateClusterConfiguration, using the console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, CDK, or Terraform. This is the same workflow you already use for broker configuration changes.
If the configuration fails to apply, review the errors. For details, see the troubleshooting section in the Amazon MSK Developer Guide.
After the configuration is accepted, Amazon MSK applies it through a rolling restart. Wait until the operation reports SUCCESS. If it reports FAILED, a broker could not apply the change. The rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the configuration and re-apply to recover.
Confirm clients can connect through the custom domain:
If your topic list is returned, clients are successfully connecting through your custom domain. If the operation reported SUCCESS but clients cannot connect, the cluster-side configuration is correct, but your networking layer likely needs attention.
This step is important. Clients can be disconnected if the networking is not ready. Kafka clients do not keep using the original address they bootstrapped with. On a periodic metadata refresh, each client learns the broker’s advertised listener. The client uses that address for all subsequent connections. When you apply a custom domain name, that advertised address changes from the default name that Amazon MSK generates to your custom domain, so at the next metadata refresh every client connects over the custom domain. For this reason, the connectivity and trust layer described in What you set up, and what Amazon MSK manages is a prerequisite, not a follow-up task.
The safe sequence, which is also how customers move from Amazon DNS to a custom domain today, is two phases:
custom.advertised.listeners changes what the brokers advertise. At the next metadata refresh, clients pick up the custom domain and cut over to it automatically.Because the path already exists, this cutover is transparent: as Amazon MSK applies the change broker by broker, clients reconnect on their own, with no restart or reconfiguration.
When you scale the cluster or a broker is replaced during automated healing, Amazon MSK automatically applies the configuration to the new broker, resolving {broker_id} for its ID, with no manual steps required on the cluster side. Remember to add the corresponding NLB listener, target group, and DNS record for any new broker, because the networking layer does not auto-scale.
Custom domain name configuration turns a per-broker CLI workaround into a single, validated, cluster-wide Amazon MSK configuration property. It works identically on ZooKeeper and KRaft, persists through scaling and failover, and flows through your existing Terraform, CloudFormation, and CLI workflows. If you rely on custom domain names, we recommend adopting the static configuration now.
This capability is available on all Amazon MSK Provisioned clusters with Standard and Express brokers, in all AWS Regions where Amazon MSK Provisioned is available. To get started, see the Amazon MSK Developer Guide and the end-to-end networking walkthrough in Configure a custom domain name for your Amazon MSK cluster.