Security updates for Wednesday

Post Syndicated from jzb original https://lwn.net/Articles/1036567/

Security updates have been issued by AlmaLinux (httpd, kernel, and kernel-rt), Debian (python-eventlet and python-h2), Mageia (aide, gnutls, tomcat, and vim), Oracle (httpd, mod_http2, postgresql:15, python3.11, python3.12, python3.9, and udisks2), Red Hat (kernel, postgresql, postgresql:12, and postgresql:15), SUSE (dcmtk, jupyter-bqplot-jupyterlab, kured, libudisks2-0, munge, python-eventlet, python-future, python311-eventlet, rekor, traefik2, and ucode-intel), and Ubuntu (linux-aws, linux-azure-5.15, linux-gcp-6.8, linux-gke, linux-gkeop, linux-hwe-6.8, linux-nvidia,
linux-nvidia-6.8, linux-nvidia-lowlatency, linux-raspi, linux-gke, linux-ibm-5.15, linux-kvm, and protobuf).

Indirect Prompt Injection Attacks Against LLM Assistants

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/09/indirect-prompt-injection-attacks-against-llm-assistants.html

Really good research on practical attacks against LLM agents.

“Invitation Is All You Need! Promptware Attacks Against LLM-Powered Assistants in Production Are Practical and Dangerous”

Abstract: The growing integration of LLMs into applications has introduced new security risks, notably known as Promptware­—maliciously engineered prompts designed to manipulate LLMs to compromise the CIA triad of these applications. While prior research warned about a potential shift in the threat landscape for LLM-powered applications, the risk posed by Promptware is frequently perceived as low. In this paper, we investigate the risk Promptware poses to users of Gemini-powered assistants (web application, mobile application, and Google Assistant). We propose a novel Threat Analysis and Risk Assessment (TARA) framework to assess Promptware risks for end users. Our analysis focuses on a new variant of Promptware called Targeted Promptware Attacks, which leverage indirect prompt injection via common user interactions such as emails, calendar invitations, and shared documents. We demonstrate 14 attack scenarios applied against Gemini-powered assistants across five identified threat classes: Short-term Context Poisoning, Permanent Memory Poisoning, Tool Misuse, Automatic Agent Invocation, and Automatic App Invocation. These attacks highlight both digital and physical consequences, including spamming, phishing, disinformation campaigns, data exfiltration, unapproved user video streaming, and control of home automation devices. We reveal Promptware’s potential for on-device lateral movement, escaping the boundaries of the LLM-powered application, to trigger malicious actions using a device’s applications. Our TARA reveals that 73% of the analyzed threats pose High-Critical risk to end users. We discuss mitigations and reassess the risk (in response to deployed mitigations) and show that the risk could be reduced significantly to Very Low-Medium. We disclosed our findings to Google, which deployed dedicated mitigations.

Defcon talk. News articles on the research.

Prompt injection isn’t just a minor security problem we need to deal with. It’s a fundamental property of current LLM technology. The systems have no ability to separate trusted commands from untrusted data, and there are an infinite number of prompt injection attacks with no way to block them as a class. We need some new fundamental science of LLMs before we can solve this.

Use account-agnostic, reusable project profiles in Amazon SageMaker to streamline governance

Post Syndicated from Ramesh H Singh original https://aws.amazon.com/blogs/big-data/use-account-agnostic-reusable-project-profiles-in-amazon-sagemaker-to-streamline-governance/

Amazon SageMaker now supports account-agnostic project profiles, so you can create reusable project templates across multiple AWS accounts and organizational units. In this post, we demonstrate how account-agnostic project profiles can help you simplify and streamline the management of SageMaker project creation while maintaining security and governance features. We walk through the technical steps to configure account-agnostic, reusable project profiles, helping you maximize the flexibility of your SageMaker deployments.

New feature: Account-agnostic project profiles

Previously, SageMaker provided the ability to create project profiles, which required selecting an AWS account and AWS Region at the time of profile creation. This feature provides you the flexibility to insert the AWS account and Region dynamically when creating projects.

SageMaker now supports generic, account-agnostic project profiles (templates) in SageMaker domains, so domain administrators can define project configurations one time and reuse them across multiple AWS accounts and Regions.

Project profiles are no longer tied to a specific AWS account or Region. Instead, platform teams can reference an account pool—a new domain entity that enables dynamic account and Region selection at the time of project creation, based on custom enterprise authorization policies or user-specific logic. This decoupling of profile definitions from static deployment settings is designed to simplify governance, reduce duplication, and accelerate onboarding across large-scale data and machine learning (ML) environments.

Account-agnostic project profiles offer the following key benefits:

  • Project creators benefit from a more flexible experience – During project creation, project creators can select from a personalized list of authorized AWS accounts and Regions, powered by custom resolution strategies or predefined account pools.
  • The feature streamlines project profile governance – This model is intended to enable organizations operating across many different accounts to scale efficiently across those accounts, while preserving organization’s centralized control and permission boundaries.

Customer spotlight

As a large data-driven organization, Bayer AG looks to harness the power of data, analytics, and ML to help researchers and engineers accelerate pharmaceutical innovation. With the ability to create account agnostic templates and reusable templates in SageMaker, the research teams at Bayer can innovate faster without platform and engineering overhead.

“At Bayer, we use Amazon SageMaker Unified Studio as a unified, governed workspace that brings together data from multiple AWS accounts—enabling our users to run analytics, build pipelines, and train models as part of their day-to-day work. With the new capability to create account-agnostic templates, our platform team can publish reusable templates once, and teams can select the right authorized AWS account at project creation—without relying on platform hand-offs. This will support faster onboarding, improved agility, and consistent governance as we scale ML across our global operations.”

— Avinash Reddy Erupaka, Principal Engineering Lead, Drug Innovation Platform, Bayer

Solution overview

For our example use case, a leading pharmaceutical company has implemented SageMaker to manage their enterprise-wide data governance initiatives. The organization faces the complex challenge of managing thousands of AWS accounts across their global operations.

To streamline this process, their platform administrator needs to develop a system of reusable project profiles that map to specific account pools, organized according to the company’s organizational structure. For instance, they’ve created a specialized Corporate HR project profile tailored to meet the Corporate HR team’s specific requirements, as well as a comprehensive Data Engineer project profile designed for data engineering teams operating across North America, Asia-Pacific, and European Regions. This strategic approach helps data engineers efficiently create new projects using these preconfigured profiles while selecting from pre-authorized account and Region combinations. This structure strikes an optimal balance between operational flexibility and enhanced security and governance features.

In the following sections, we provide a detailed, step-by-step implementation guide for this solution.

Prerequisites

For this walkthrough, you must have the following prerequisites:

  • An AWS account – If you don’t have an account, you can create one. The account should have permission to do the following:
  • SageMaker domain – For instructions, refer to Create a domain – quick setup.
  • AWS CLI installed – The AWS Command Line Interface (AWS CLI) version 2.11 or later.
  • Python installed – Python 3.8 or later (if using custom Lambda handlers).
  • IAM permissions – The following IAM permissions are required:
    • sagemaker:CreateProject
    • sagemaker:CreateProjectProfile
    • datazone:CreateAccountPool

Platform administrator tasks

The platform administrator is responsible for two key setup tasks: creating account pools and establishing project profiles associated with these pools. This section provides the steps to accomplish both crucial processes.

Create account pools

There are two ways to create account pools:

  • For static account sources, provide a list of accounts and Regions
  • For dynamic account sources, use a custom Lambda handler to authorize account and Region pair information

As of this writing, the creation, update, and deletion of account pools are only supported in the AWS CLI.

For creating account pools, use the create-account-pool command and provide the resources. We used the following commands to create account pools for our example use case. Replace the relevant values with your own resources, such as domain identifier, account, and Region.

First, create the account pool hr-accountpool with a single AWS account. In the following command, the parameter MANUAL refers to the mechanism by which an account is chosen from the pool at project creation time. Because the platform admin is manually choosing the accounts, the resolution strategy is set to MANUAL.

aws datazone create-account-pool --domain-identifier dzd_5yxxxxxxxxxxxx --name hr-accountpool --resolution-strategy MANUAL --account-source '{"accounts": [{"awsAccountId": "633xxxxxxxxx", "supportedRegions": ["us-east-1"], "awsAccountName": "HRaccount"}]}'

Next, create the account pool namer-data-engg-pool with multiple AWS accounts. Use the same code to create account pools for the EMEA and APAC Regions:

aws datazone create-account-pool --domain-identifier dzd_5yxxxxxxxxxxxx --name namer-data-engg-pool --resolution-strategy MANUAL --account-source '{"accounts": [{"awsAccountId": "633xxxxxxxxx", "supportedRegions": ["us-east-1"], "awsAccountName": "usaccount1"}, {"awsAccountId": "635xxxxxxxxx ", "supportedRegions": ["us-east-1"], "awsAccountName": "usaccount2"}]}'

You will use these account pools in subsequent steps to create project profiles.

To verify account pool creation, use the following command:

aws datazone list-account-pools --domain-identifier <domain-id>

If you have an external permissioning system, you can use the following custom Lambda command to create your account pool that will dynamically resolve during project creation:

aws datazone create-account-pool --domain-identifier dzd_cdy9yy904sxxxx --name custom- accountpool --resolution-strategy MANUAL --account-source '{"customAccountPoolHandler": {"lambdaFunctionArn": "<<Lambda ARN>>","lambdaExecutionRoleArn": "<<Lambda execution role>>"}}'

Create project profiles and account pool assignments

In this step, we establish project profiles and connect them to authorized account pools. There are three possible scenarios for setting up project profiles.

Scenario 1: Project profile associated with a single account pool

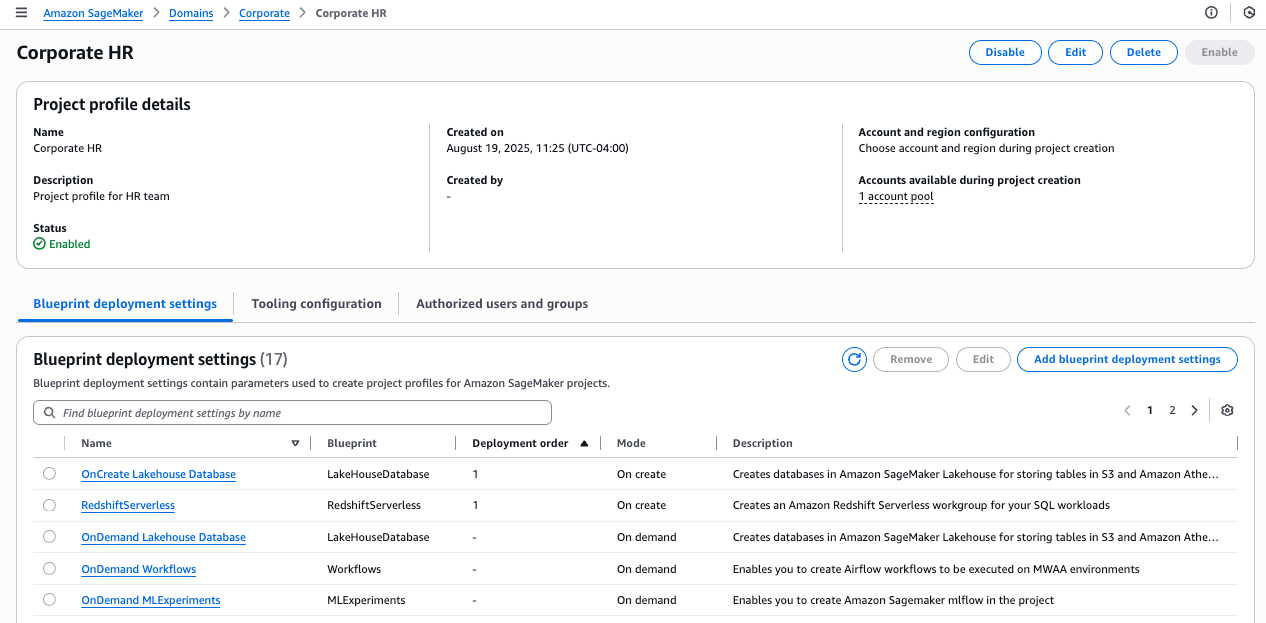
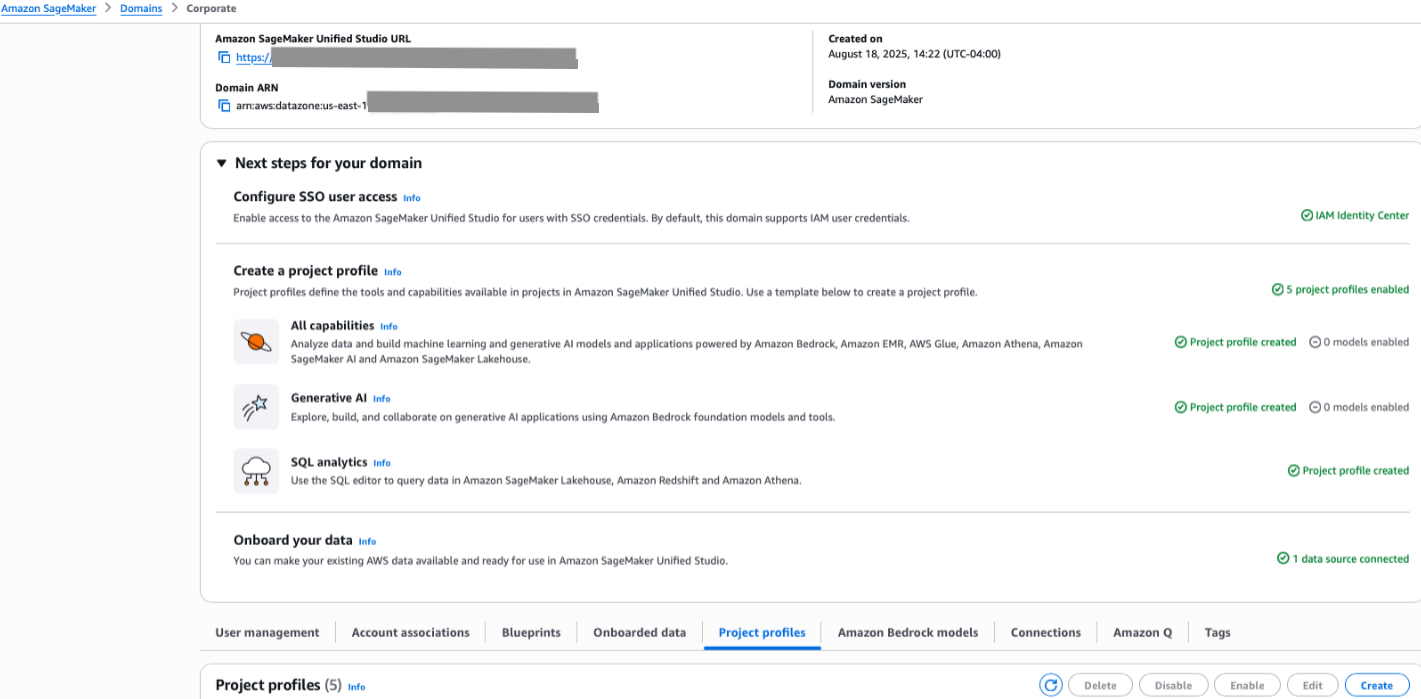
This is the simplest configuration, where one project profile is mapped to a single account pool. In the following steps, we create a project profile for the Corporate HR team and tie it to the HR account pool:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. On the Project profiles tab, choose Create.
  3. Enter a name and description for your profile.
  4. Choose an appropriate project profile template that aligns with your project’s needs.
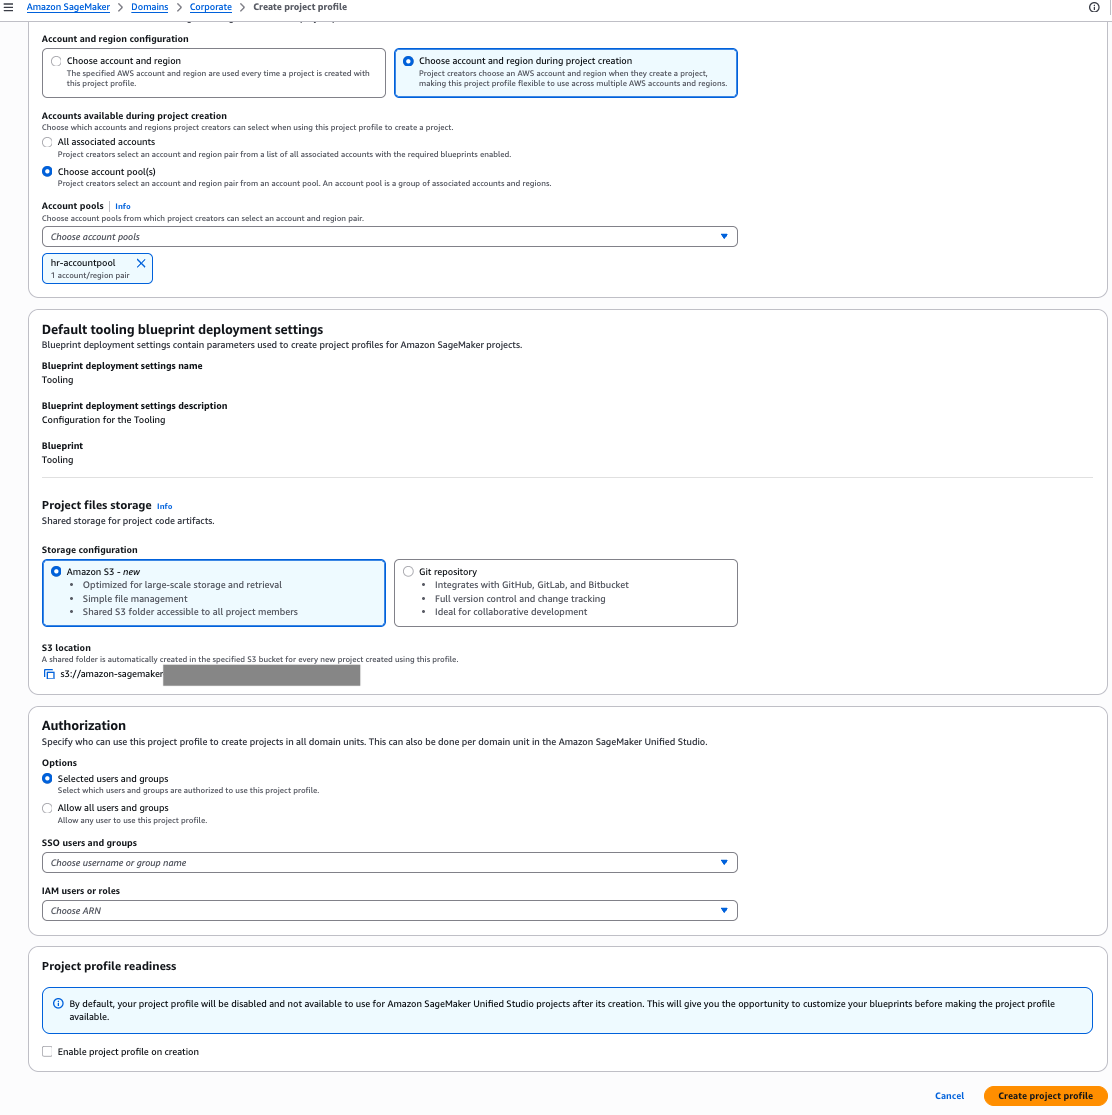
  5. Select Choose account and region during project creation.
  6. Select Choose account pool(s) and choose the account pool you created for the HR team.
  7. Leave the remaining settings as default and choose Create project profile.
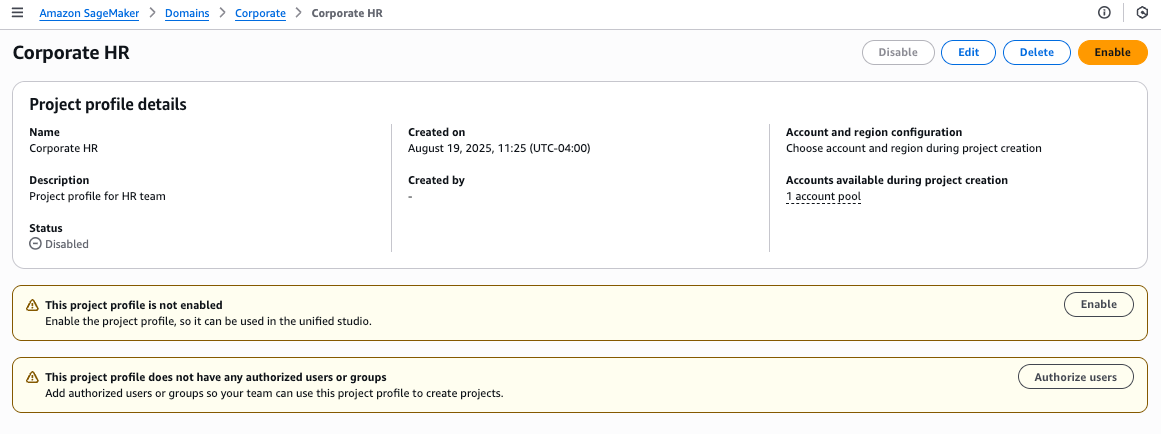
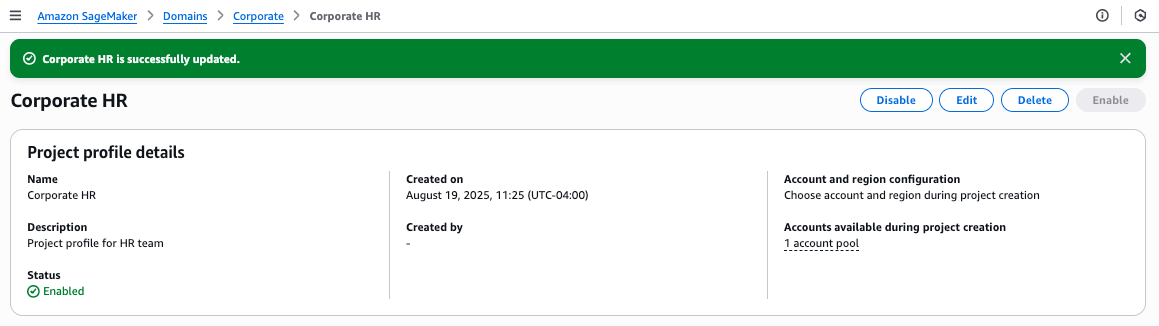
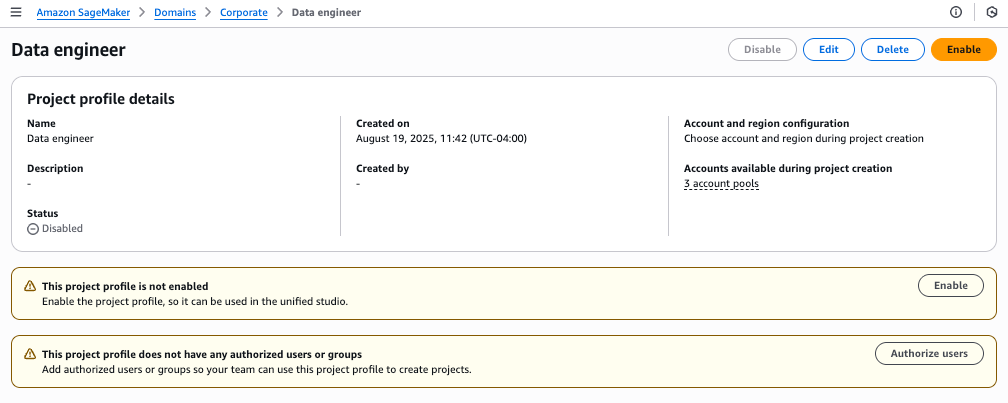
  8. On the project details page, choose Enable to activate your profile.
  9. Choose Enable in the confirmation pop-up to proceed.

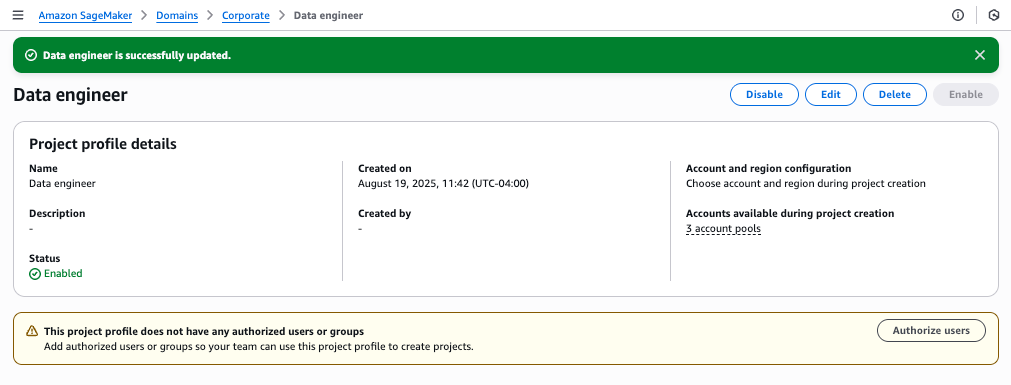
You will see a success message confirming that the Corporate HR profile has been created and linked to one account pool.

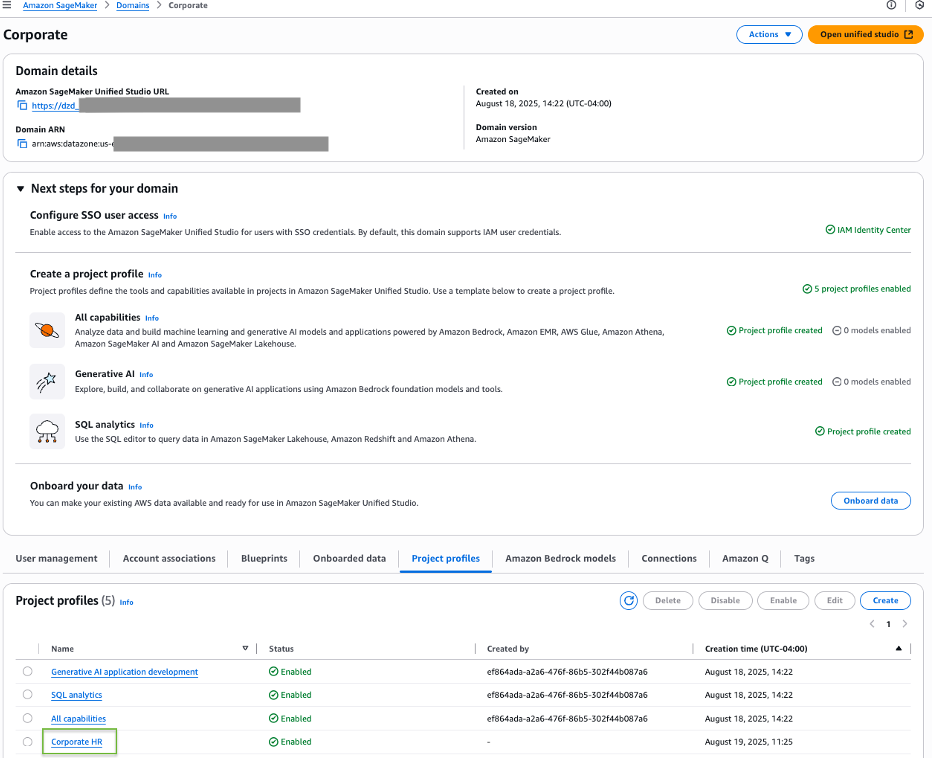
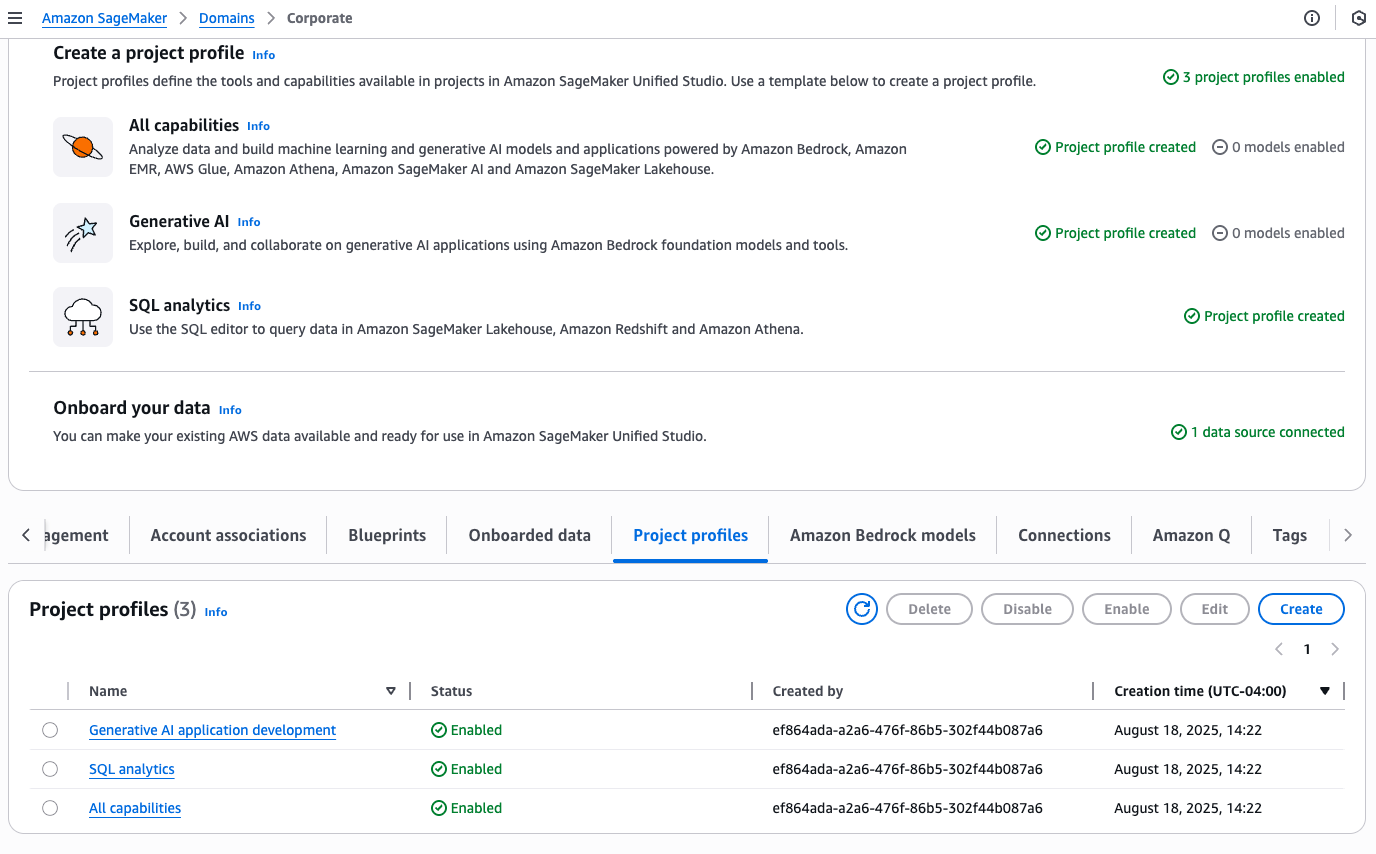
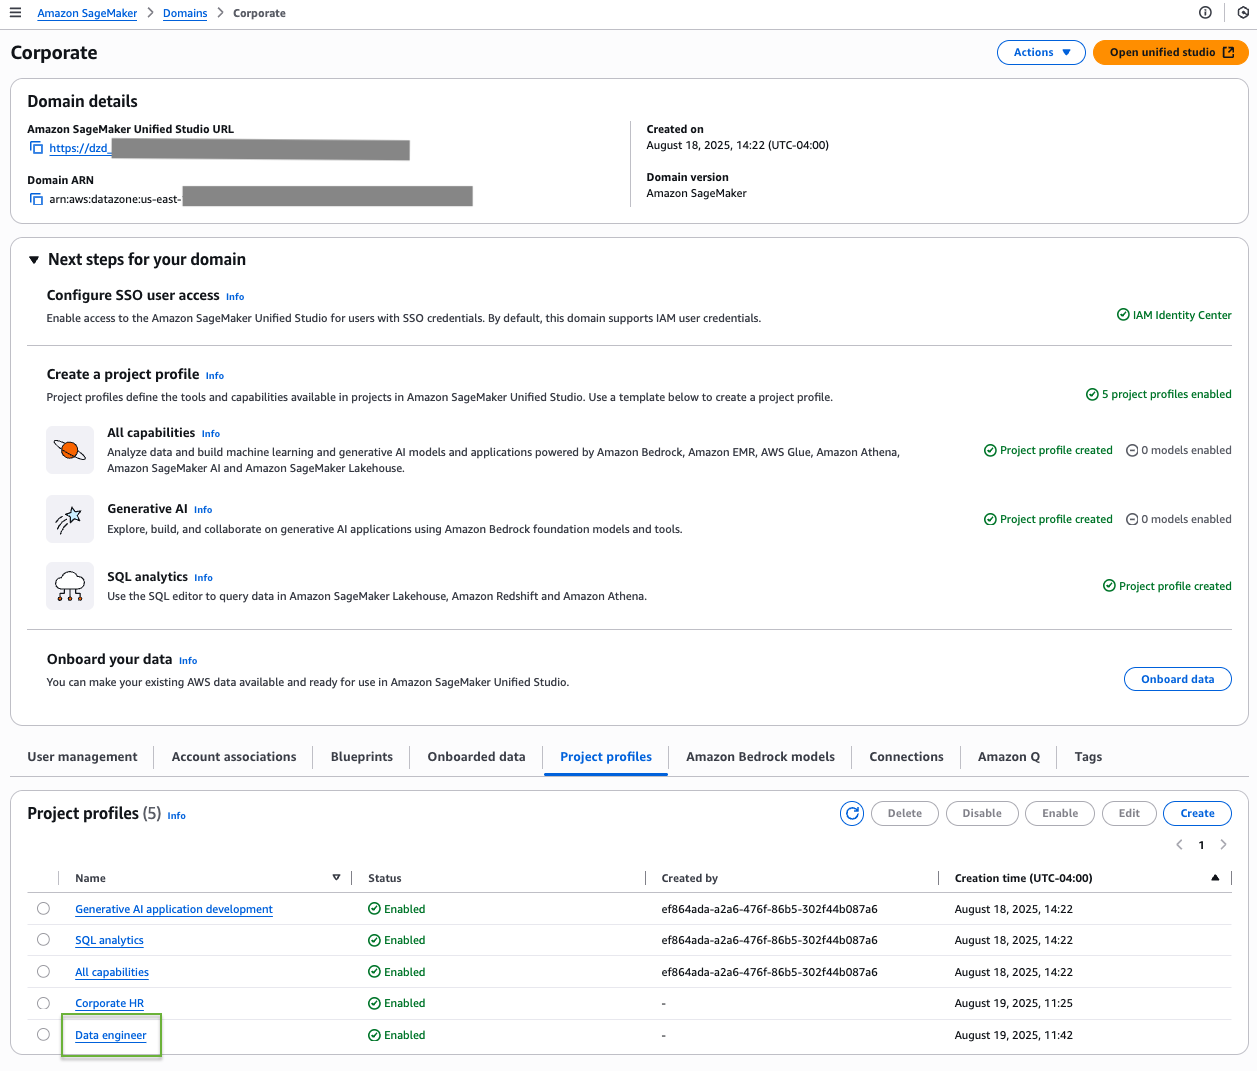
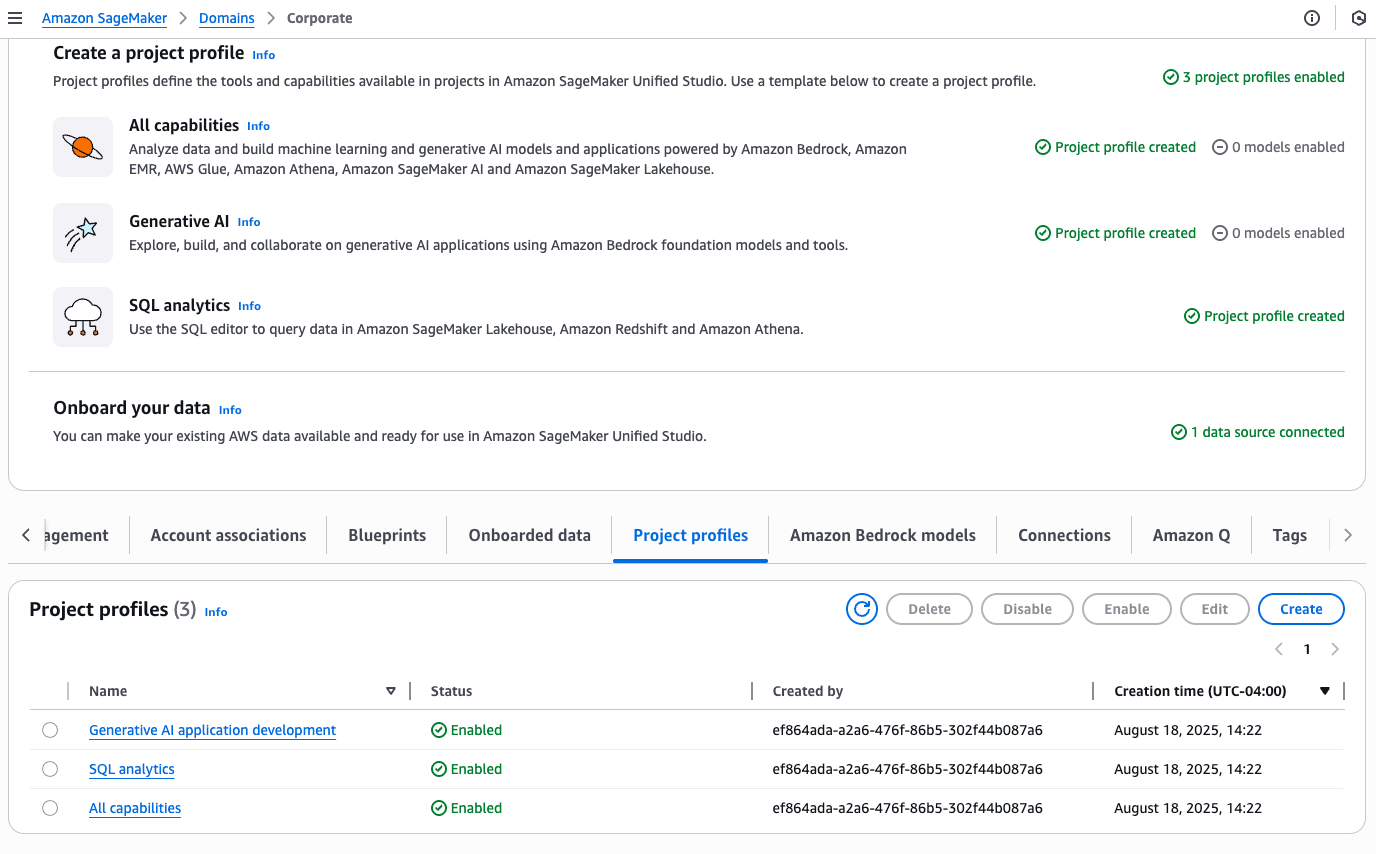
On the Project profiles tab, you should now see your newly created Corporate HR profile listed among the available project profiles.

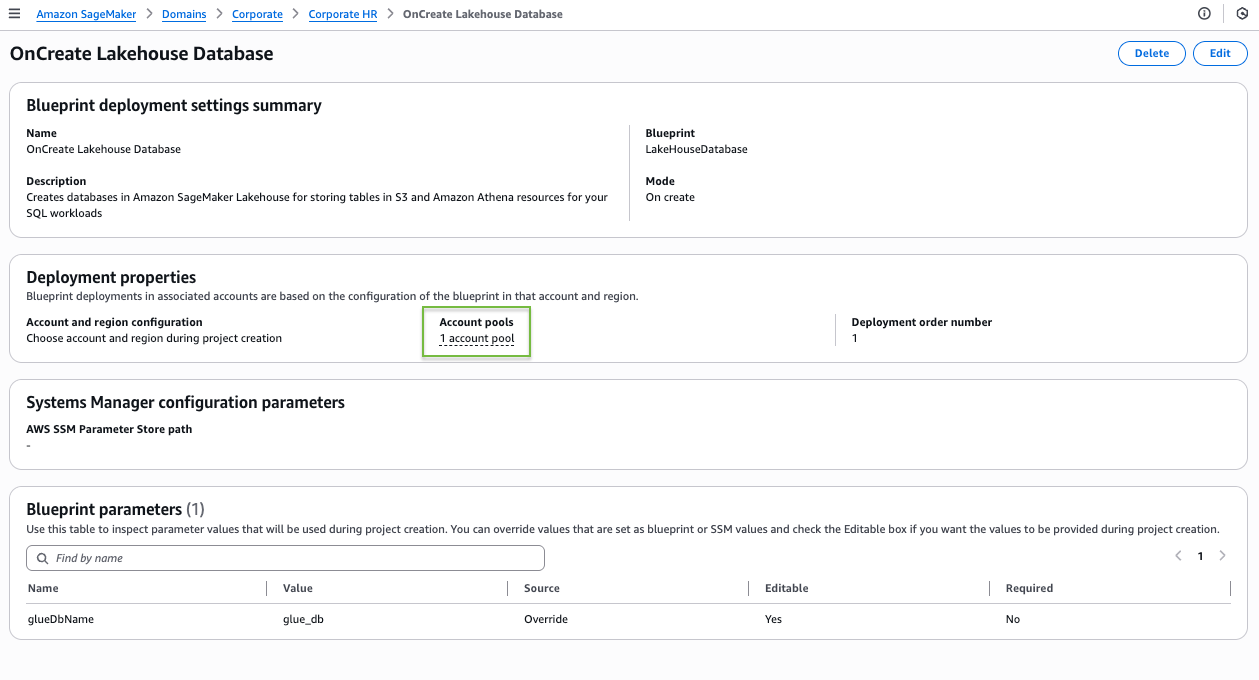
To explore further, navigate to the Corporate HR project profile and choose the Blueprints tab to see a list of available blueprints. Choose a blueprint to view its details.

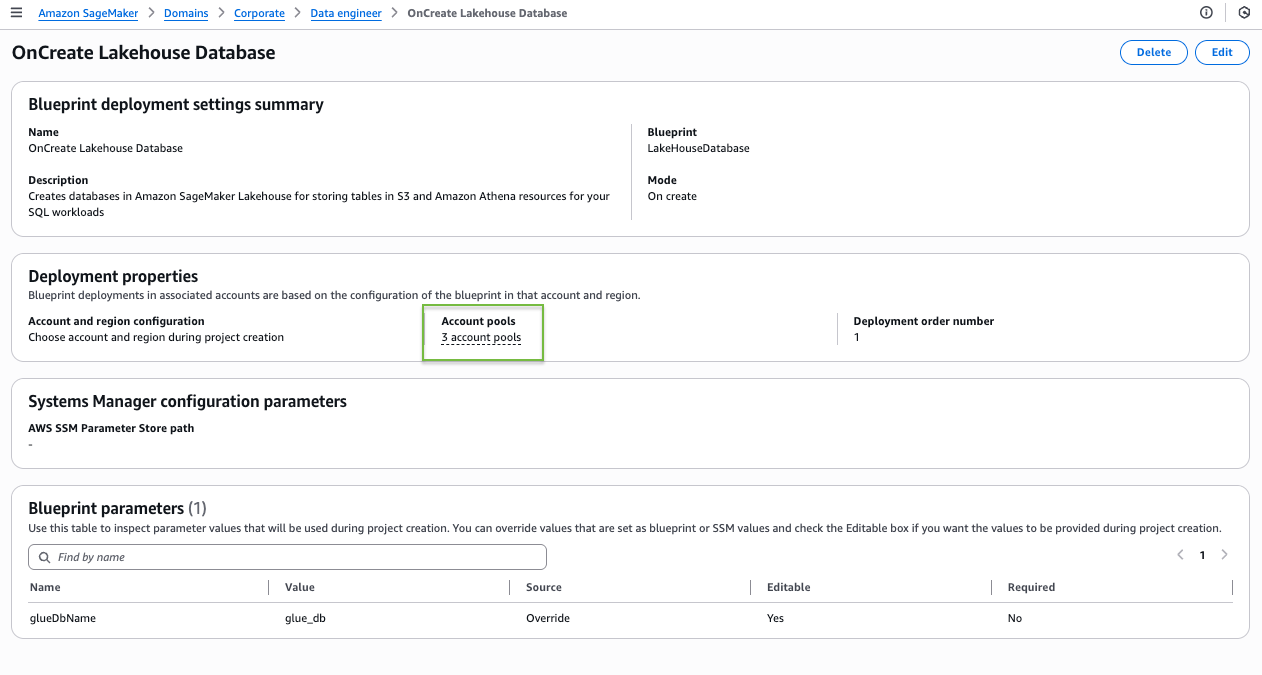
On the blueprint details page, the blueprint shows as deployable to the single account pool you associated with this project profile.

Scenario 2: Project profile associated with multiple account pools

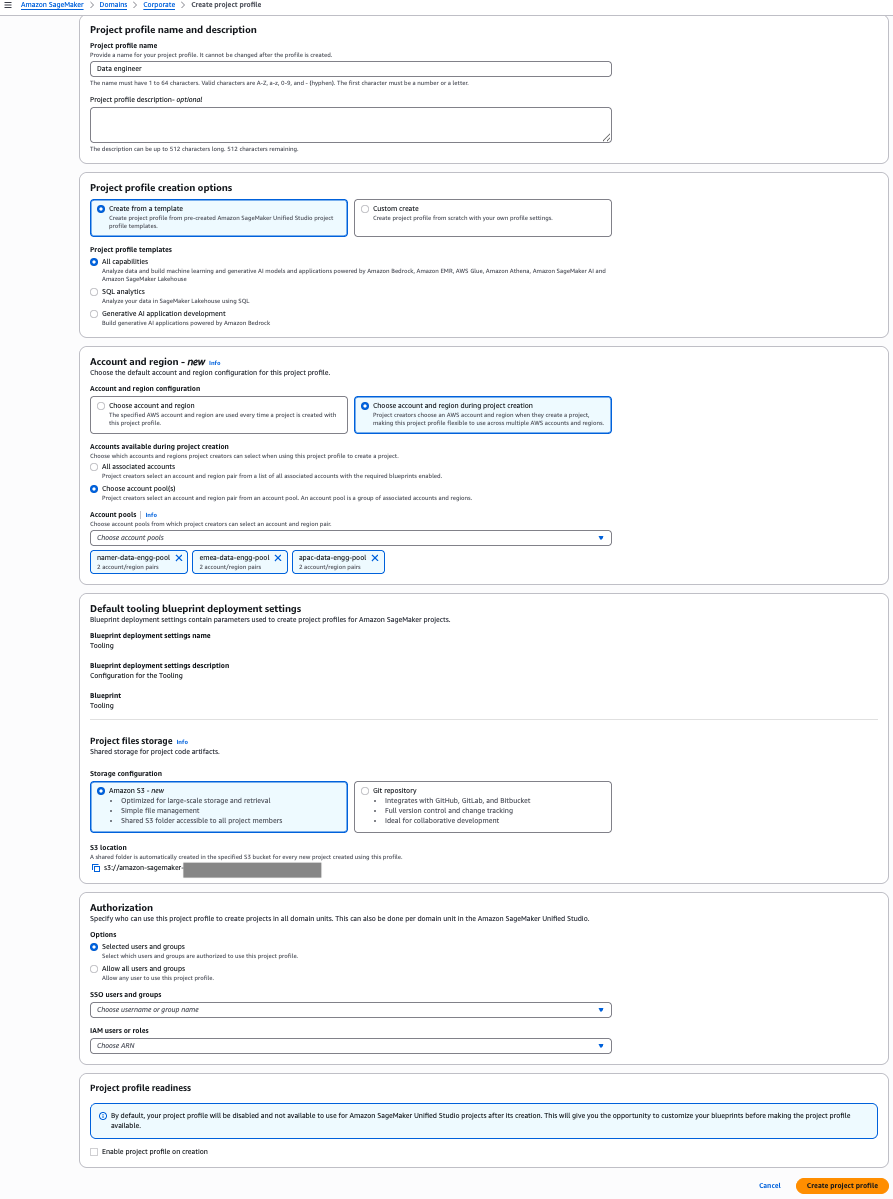
In this example, we create a project profile for a global Data Engineering team, connecting it to three Regional account pools: NAMER (North America), APAC (Asia Pacific), and EMEA (Europe, Middle East, and Africa). Complete the following steps:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. On the Project profiles tab, choose Create.
  3. Enter a name and description for your profile.
  4. Choose an appropriate project profile template that aligns with your project’s needs.
  5. Select Choose account and region during project creation.
  6. Select Choose account pool(s) and choose all three Regional pools:
    1. NAMER Data Engineering team
    2. EMEA Data Engineering team
    3. APAC Data Engineering team
  7. Leave the remaining settings as default and choose Create project profile.
  8. On the project details page, choose Enable to activate your profile.
  9. Choose Enable in the confirmation pop-up to proceed.

You will see a success message confirming the Data Engineer profile creation. The profile will show connections to all three Regional account pools.

You can find your new profile listed on the Project profiles tab.

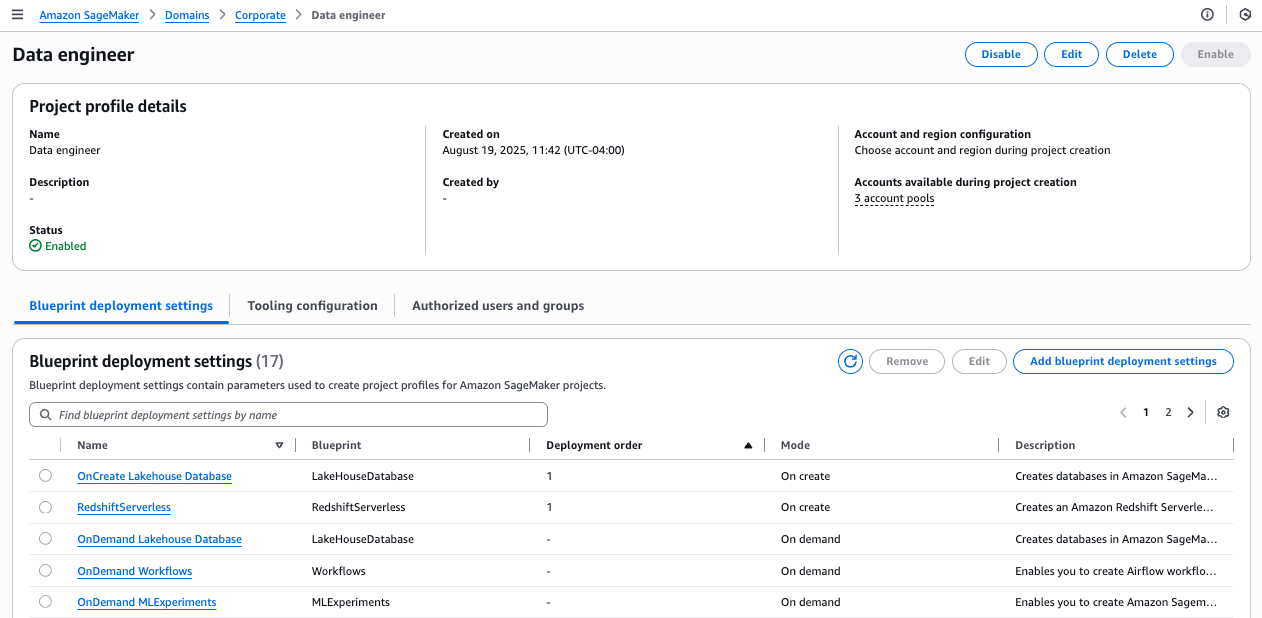
Navigate to your project profile and choose the Blueprints tab to see a list of available blueprints. Choose a blueprint to view its details.

On the blueprint details page, the blueprint shows as deployable to the three account pools you associated with this project profile.

Scenario 3: Project profile with all associated accounts

In this scenario, we create a project profile linked to all the associated accounts for this domain. Complete the following steps:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. On the Project profiles tab, choose Create.
  3. Enter a name and description for your profile.
  4. Choose an appropriate project profile template that aligns with your project’s needs.
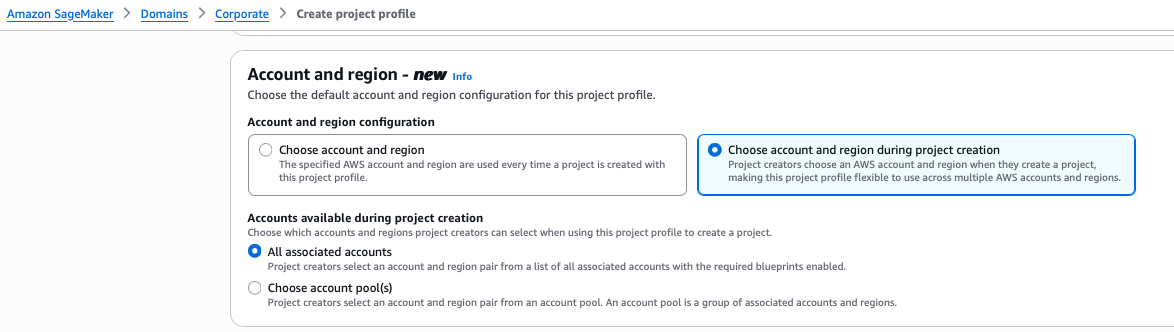
  5. Select Choose account and region during project creation.
  6. Select All associated accounts.
  7. Leave the remaining settings as default and choose Create project profile.

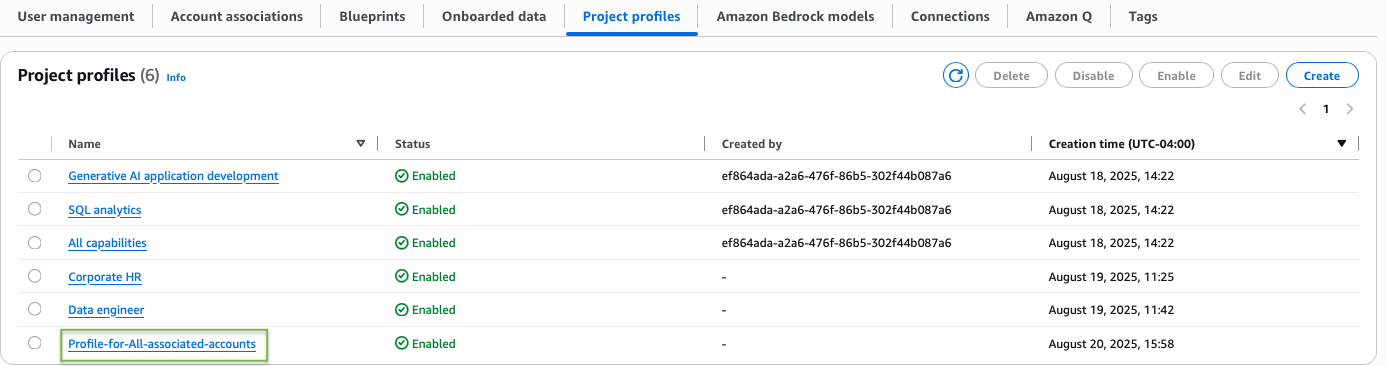
You can find your new profile listed on the Project profiles tab.

Project owner tasks

Now that the administrator has created project profiles for the account pools, project owners can log in to SageMaker to create projects for their account pools. In this section, we demonstrate the procedure to create a project using an account-agnostic project profile with a single account pool. You can use the same procedure to create projects using an account-agnostic project profile with multiple account pools.

For this scenario, Sarah from HR will create a project for the HR team, using the Corporate HR team profile that is associated with the HR account pool.

  1. On the SageMaker portal, choose Create project.
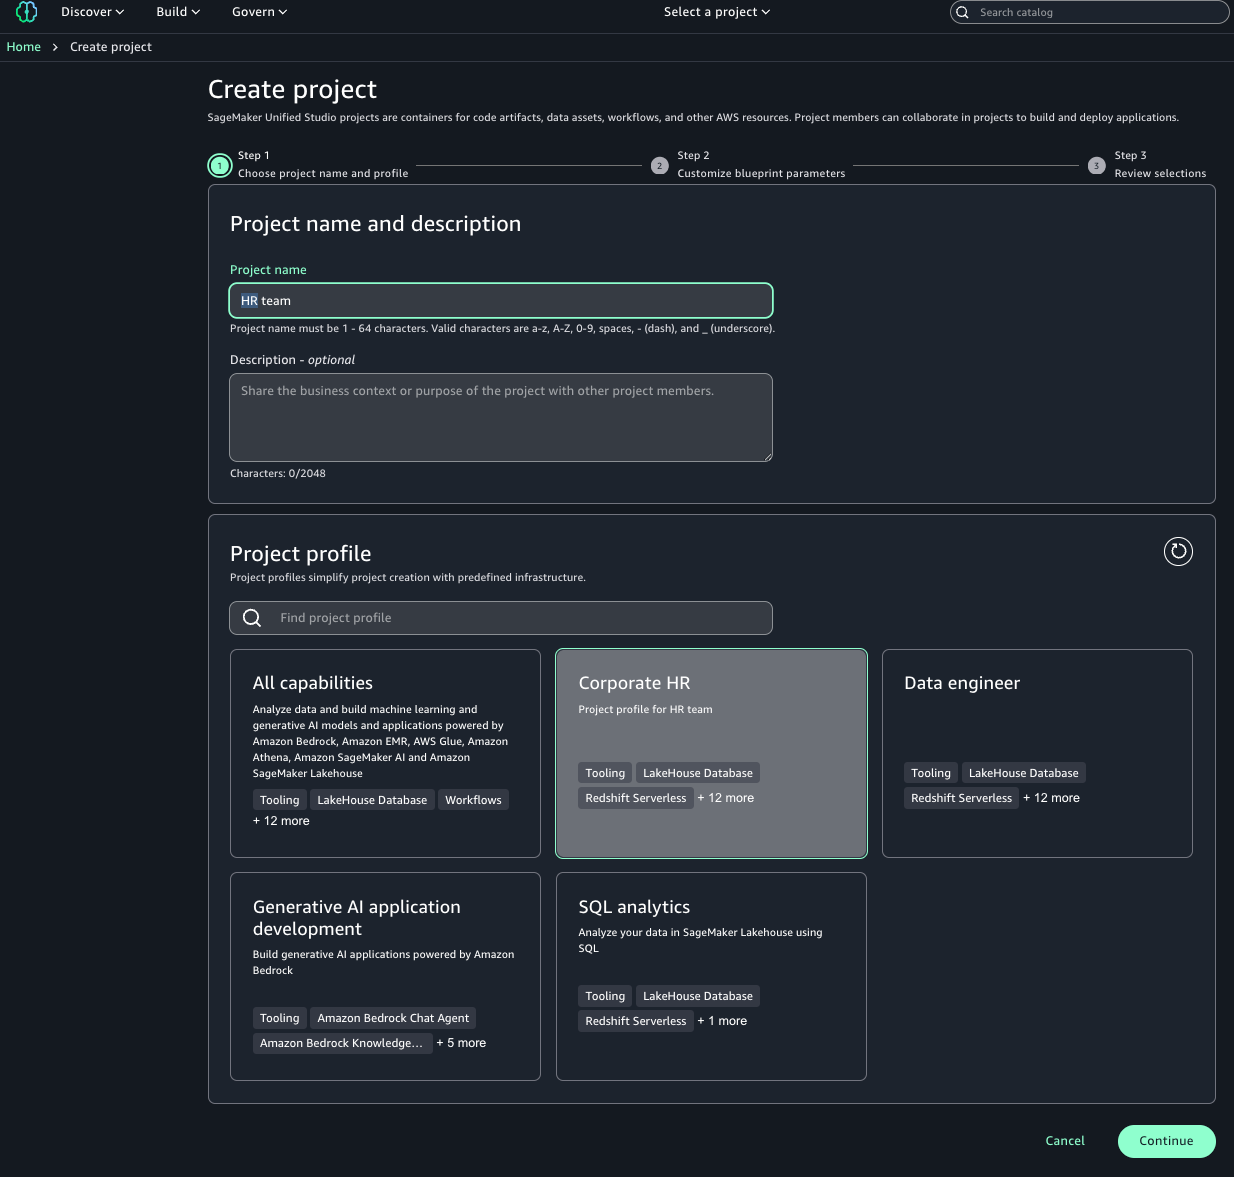
  2. Enter a name and optional description.
  3. Choose the Corporate HR project profile.
  4. Choose Continue.
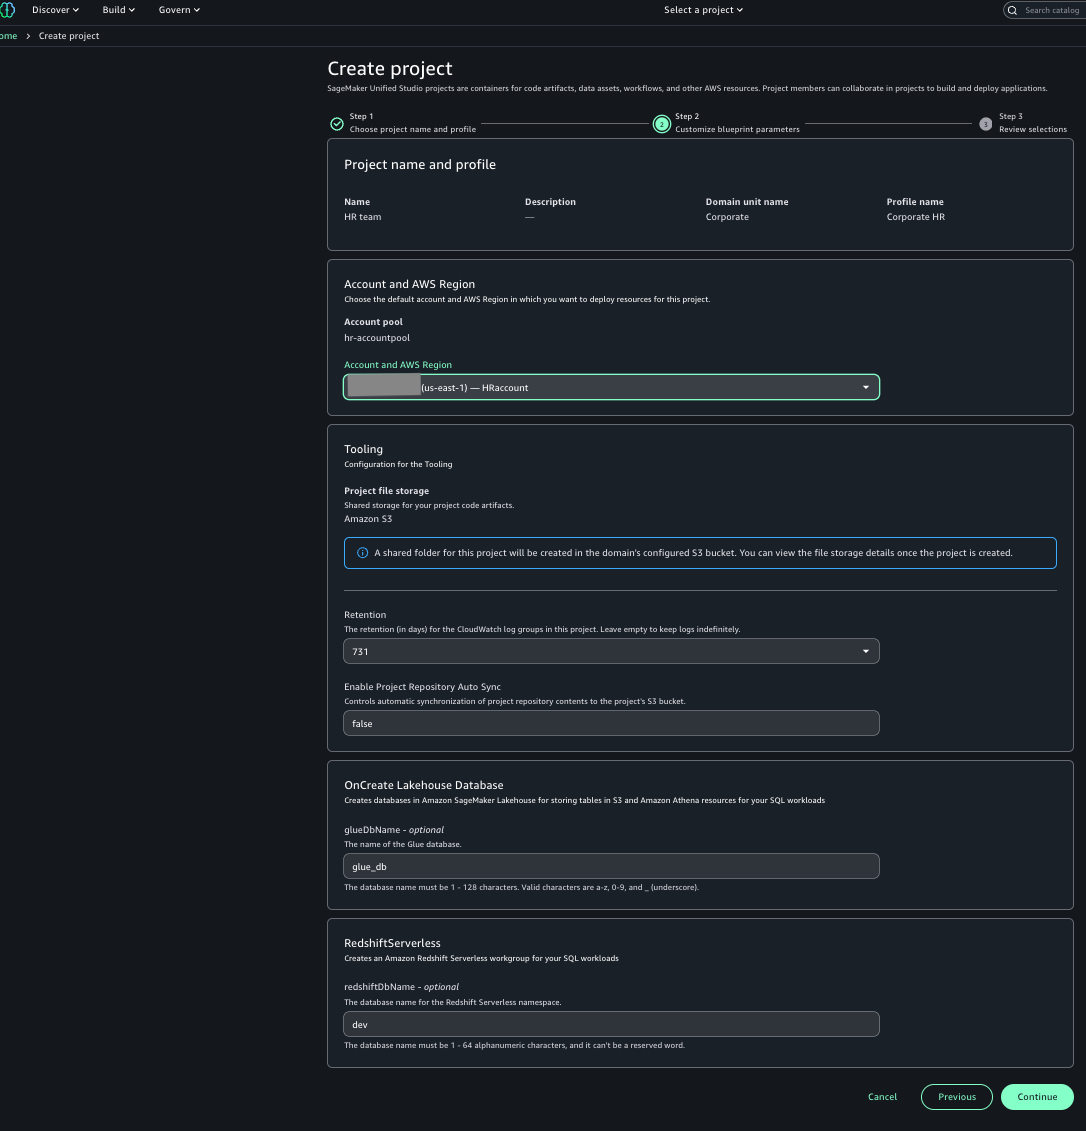
  5. For Account and AWS Region, choose the HR account.
  6. Choose Continue.
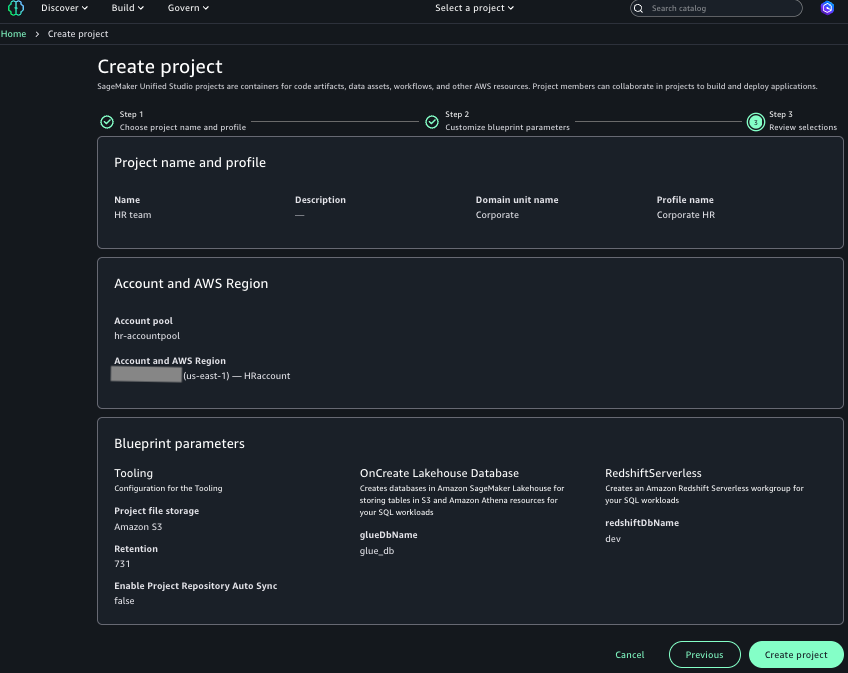
  7. Review the information and choose Create project.

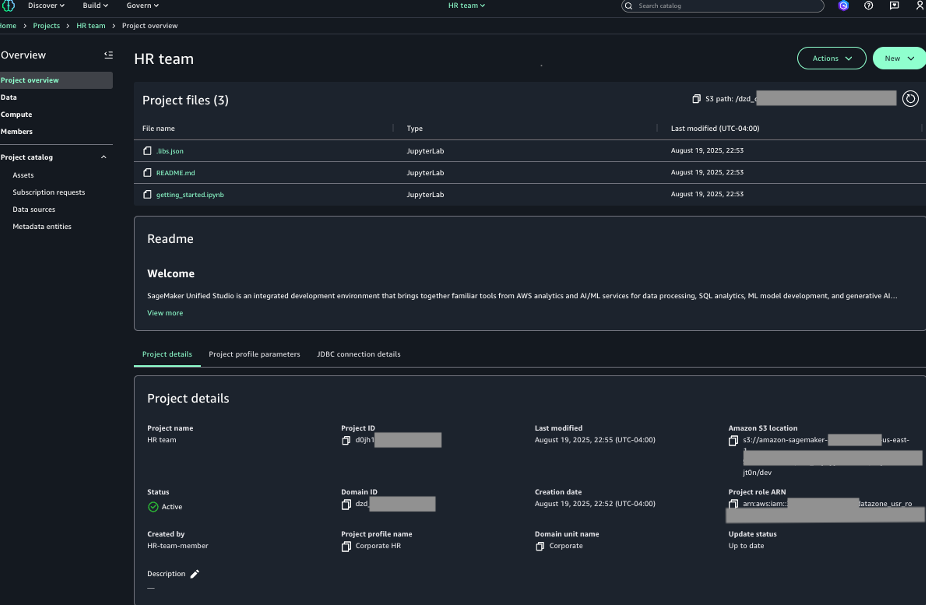
You can view the successfully created project.

Clean up

To clean up resources, complete the following steps:

  1. Delete the projects using the AWS CLI:
    aws sagemaker delete-project --project-name <project-name>

  2. Delete the account pools:
    aws datazone delete-account-pool --domain-identifier <domain-id> --name <pool-name>

Conclusion

In this post, we discussed how account-agnostic project profiles can help organizations simplify and streamline the management of SageMaker project creation while maintaining enhanced security and governance features. To learn more about account-agnostic project profiles in SageMaker, refer to Account pools in Amazon SageMaker Unified Studio, and demo: account-agnostic project profile in Amazon SageMaker.

About the Authors

Ramesh H Singh

Ramesh H Singh

Ramesh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon DataZone team. He is passionate about building high-performance ML/AI and analytics products that help enterprise customers achieve their critical goals using cutting-edge technology

Nira Jaiswal

Nira Jaiswal

Nira is a Principal Data Solutions Architect at AWS. Nira works with strategic customers to architect and deploy innovative data and analytics solutions. She excels at designing scalable, cloud-based platforms that help organizations maximize the value of their data investments. Nira is passionate about combining analytics, AI/ML, and storytelling to transform complex information into actionable insights that deliver measurable business value.

Somdeb Bhattacharjee

Somdeb Bhattacharjee

Somdeb is a Senior Solutions Architect specializing in data and analytics. He is part of the global healthcare and life sciences industry at AWS, helping his customers modernize their data platform solutions to achieve their business outcomes.

Brian Ross

Brian Ross

Brian is a Senior Software Development Manager at AWS. He is focused on creating delightful builder experiences for data, analytics and AI, and is currently building the next generation of Amazon SageMaker. He is based out of NYC and thinks you should be, too.

Deploy Apache YuniKorn batch scheduler for Amazon EMR on EKS

Post Syndicated from Suvojit Dasgupta original https://aws.amazon.com/blogs/big-data/deploy-apache-yunikorn-batch-scheduler-for-amazon-emr-on-eks/

As organizations successfully grow their Apache Spark workloads on Amazon EMR on EKS, they may seek to optimize resource scheduling to further enhance cluster utilization, minimize job queuing, and maximize performance. Although Kubernetes’ default scheduler, kube-scheduler, works well for most containerized applications, it lacks feature sets capable of managing complex big data workloads with specific requirements such as gang scheduling, resource quotas, job priorities, multi-tenancy, and hierarchical queue management. This limitation can result in inefficient resource utilization, longer job completion times, and increased operational costs for organizations running large-scale data processing workloads.

Apache YuniKorn addresses these limitations by providing a custom resource scheduler specifically designed for big data and machine learning (ML) workloads running on Kubernetes. Unlike kube-scheduler, YuniKorn offers features such as gang scheduling, making sure all containers of a Spark application start together, resource fairness amongst multiple tenants, priority and preemption capabilities, and queue management with hierarchical resource allocation. For data engineering and platform teams managing large-scale Spark workloads on Amazon EMR on EKS, YuniKorn can improve resource utilization rates, reduce job completion times, and provide improved resource allocation for multi-tenant clusters. This is particularly valuable for organizations running mixed workloads with varying resource requirements, strict SLA requirements, or complex resource sharing policies across different teams and applications.

This post explores Kubernetes scheduling fundamentals, examines the limitations of the default kube-scheduler for batch workloads, and demonstrates how YuniKorn addresses these challenges. We discuss how to deploy YuniKorn as a custom scheduler for Amazon EMR on EKS, its integration with job submissions, how to configure queues and placement rules, and how to establish resource quotas. We also show these features in action through practical Spark job examples.

Understanding Kubernetes scheduling and the need for YuniKorn

In this section, we dive into the details of Kubernetes scheduling and the need for YuniKorn.

How Kubernetes scheduling works

Kubernetes scheduling is the process of assigning pods to nodes within a cluster while considering resource requirements, scheduling constraints, and isolation constraints. The scheduler evaluates each pod individually against all schedulable worker nodes, considering multiple factors, including resource requirements such as CPU, memory and I/O requests, node affinity preferences for specific node characteristics, inter-pod affinity and anti-affinity rules that determine whether the pods should be distributed across multiple worker nodes or require colocation, taints and tolerations that dictate scheduling constraints, and Quality of Service classifications that influence scheduling priority.

The scheduling process operates through a two-phase approach. During the filtering phase, the scheduler identifies all worker nodes that could potentially host the pod by eliminating those that don’t meet the basic requirements. The scoring phase then ranks all feasible worker nodes using scoring algorithms to determine the optimal placement, ultimately selecting the highest-scoring node for pod assignment.

Default implementation of kube-scheduler

kube-scheduler serves as the Kubernetes default scheduler. This scheduler operates on a pod-by-pod basis, treating each scheduling decision as an independent operation without consideration for the broader application context.When kube-scheduler processes scheduling requests, it follows a continuous workflow. The API server is monitored for newly created pods awaiting node assignment, applies filtering logic to eliminate unsuitable worker nodes, executes its scoring algorithm to rank the remaining candidates, binds the selected pod to the optimal node, and repeats the process with the next unscheduled pod in the queue.This individual pod scheduling approach works well for microservices and web applications where each pod has fewer interdependencies. However, this design creates significant challenges when applied to distributed big data frameworks like Spark that require coordinated scheduling of multiple interdependent pods.

Challenges using kube-scheduler for batch jobs

Batch processing workloads, particularly those built on Spark, present different scheduling requirements that expose limitations in kube-scheduler algorithm. Such applications consist of multiple pods that must operate as a cohesive unit, yet kube-scheduler lacks the application-level awareness necessary to handle coordinated scheduling requirements.

Gang scheduling challenges

The most significant challenge emerges from the need for gang scheduling, where all components of a distributed application must be scheduled simultaneously. A typical Spark application requires a driver pod and multiple executor pods running in parallel to function correctly. Without YuniKorn, kube-scheduler first schedules the driver pod without knowing the total amount of resources that the driver and executors will need together. When the driver pod starts running, it attempts to spin up the required executor pods but might fail to find sufficient resources in the cluster. This sequential approach can result in the driver being scheduled successfully while some or all executor pods remain in a pending state due to insufficient cluster capacity.This partial scheduling creates a problematic scenario where the application consumes cluster resources but can’t execute meaningful work. The partially scheduled application will hold onto allocated resources indefinitely while waiting for the missing components, preventing other applications from utilizing those resources and resulting in a deadlock situation.

Resource fragmentation issues

Resource fragmentation represents another critical issue that emerges from individual pod scheduling. When multiple batch applications compete for cluster resources, the lack of coordinated scheduling leads to scenarios where sufficient total resources exist for a given application, but they become fragmented across multiple incomplete applications. This fragmentation prevents efficient resource utilization and can leave applications in perpetual pending states.

The absence of hierarchical queue management further compounds these challenges. kube-scheduler provides limited support for hierarchical resource allocation, making it difficult to implement fair sharing policies across different tenants. Organizations can’t easily establish resource quotas that guarantee minimum allocations while setting maximum limits, nor can they implement preemption policies that allow higher-priority jobs to reclaim resources from lower-priority workloads.

The Need for YuniKorn

YuniKorn addresses these batch scheduling limitations through a set of features designed for distributed computing workloads. Unlike the pod-centric approach of kube-scheduler, YuniKorn operates with application-level awareness, understanding the relationships between different components of distributed applications and making scheduling decisions accordingly. The features are as follows:

  • Gang scheduling for atomic application deployment – Gang scheduling represents YuniKorn’s advantage for batch workloads. This capability makes sure pods belonging to an application are scheduled atomically—either all components receive node assignments, or none are scheduled until sufficient resources become available. YuniKorn’s all-or-nothing approach to scheduling minimizes resource deadlocks and partial application failures that impact kube-scheduler based deployments, resulting in more predictable job execution and higher completion rates.
  • Hierarchical queue management and resource organization – YuniKorn’s queue management system provides the hierarchical resource organization that enterprise batch processing environments require. Organizations can establish multi-level queue structures that mirror their organizational hierarchy, implementing resource quotas at each level to facilitate fair resource distribution. The scheduler supports guaranteed resource allocations that provide minimum resource commitments and maximum limits that prevent a single queue from monopolizing cluster resources.
  • Dynamic resource preemption based on priority – The preemption capabilities built into YuniKorn enable dynamic resource reallocation based on job priorities and queue policies. When higher-priority applications require resources currently allocated to lower-priority workloads, YuniKorn can gracefully stop lower-priority pods and reallocate their resources, making sure critical jobs receive the resources they need without manual intervention.
  • Intelligent resource pooling and fair share distribution – Resource pooling and fair share scheduling further enhance YuniKorn’s effectiveness for batch workloads. Rather than treating each scheduling decision in isolation, YuniKorn considers the broader resource allocation landscape, implementing fair-share algorithms that facilitate equitable resource distribution across different applications and users while maximizing overall cluster utilization.

These features add to the existing capabilities of Amazon EMR on EKS by establishing an enhanced environment in which the unique requirements of distributed computing workloads are satisfied.

Solution overview

Consider HomeMax, a fictitious company operating a shared Amazon EMR on EKS cluster where three teams regularly submit Spark jobs with distinct characteristics and priorities:

  • Analytics team – Runs time-sensitive customer analysis jobs requiring immediate processing for business decisions
  • Marketing team – Executes large overnight batch jobs for campaign optimization with predictable resource patterns
  • Data science team – Runs experimental workloads with varying resource needs throughout the day for model development and research

Without proper resource scheduling, these teams face common challenges: resource contention, job failures due to partial scheduling, and inability to guarantee SLAs for critical workloads.For our YuniKorn demonstration, we configured an Amazon EMR on EKS cluster with the following specifications:

  • Amazon EKS cluster: Four worker nodes using m5.2xlarge Amazon Elastic Compute Cloud (Amazon EC2) instances
  • Per-node resources: 8 vCPUs, 32 GiB memory
  • Total cluster capacity: 32 vCPU cores and 128 GiB memory
  • Available for Spark: Approximately 30 vCPUs and approximately 120 GiB memory (after system overhead)
  • Kubernetes version: 1.30+ (required for YuniKorn 1.6.x compatibility)

The following code shows the node group configuration:

# EKS Node Group specification
NodeGroup:
  InstanceTypes:
    - m5.2xlarge
  ScalingConfig:
    MinSize: 4
    DesiredSize: 4
    MaxSize: 4
  DiskSize: 20
  AmiType: AL2023_x86_64_STANDARD

We intentionally use a fixed-capacity cluster to provide a controlled environment that showcases YuniKorn’s scheduling capabilities with consistent, predictable resources. This approach makes resource contention scenarios more apparent and demonstrates how YuniKorn resolves them.

Amazon EMR on EKS offers robust scaling capabilities through Karpenter. The principles demonstrated in this fixed environment apply equally to dynamic environments, where YuniKorn’s capabilities complement the scaling features of Amazon EMR on EKS to optimize resource utilization during peak demand periods or when scaling limits are reached.

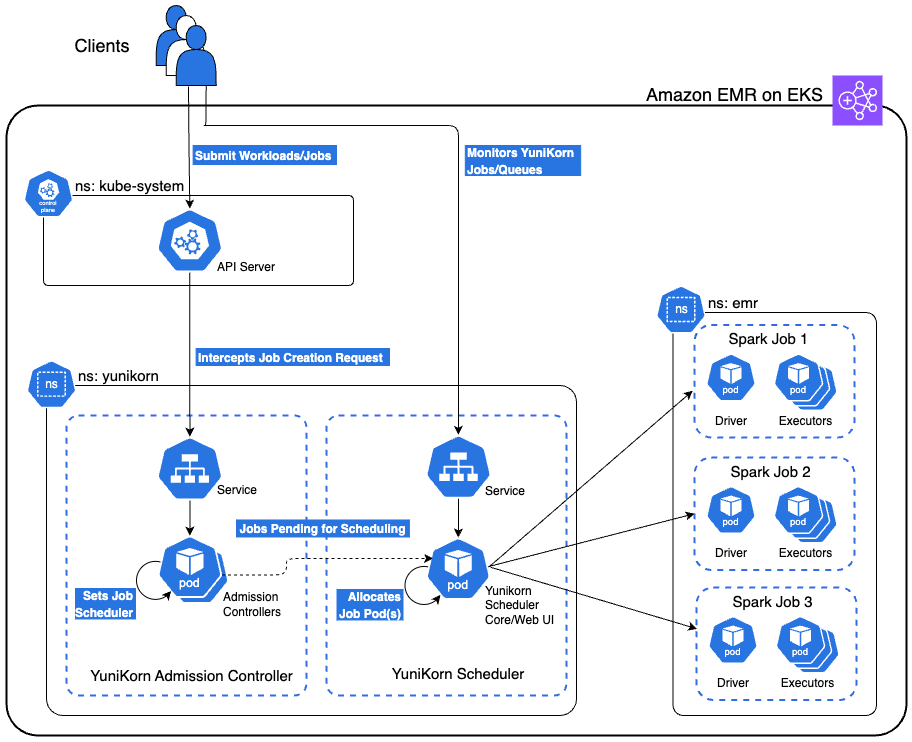
The following diagram shows the high-level architecture of the YuniKorn scheduler running on Amazon EMR on EKS. This solution also includes a secure bastion host not shown in the architecture diagram that provides access to the EKS cluster via AWS Systems Manager (SSM) Session Manager. The bastion host is deployed in a private subnet with all necessary tools pre-installed with proper permissions for seamless cluster interaction.

In the following sections, we explore YuniKorn’s queue architecture optimized for this use case. We examine various demonstration scenarios, including gang scheduling, queue-based resource management, priority-based preemption, and fair share distribution. We walk through the process of deploying an Amazon EMR on EKS cluster, implementing the YuniKorn scheduler, configuring the specified queues, and submitting Spark jobs to showcase these scenarios.

YuniKorn integration on Amazon EMR on EKS

The integration involves three key components working together: the Amazon EMR on EKS virtual cluster configuration, YuniKorn’s admission webhook system, and job-level queue annotations.

Namespace and virtual cluster foundation

The integration begins with a dedicated Kubernetes namespace where your Amazon EMR on EKS jobs will run. In our demonstration, we use the emr namespace, created as a standard Kubernetes namespace:

apiVersion: v1
kind: Namespace
metadata:
  name: emr

The Amazon EMR on EKS virtual cluster is configured to deploy all jobs within this specific namespace. When creating the virtual cluster, you specify the namespace in the container provider configuration:

aws emr-containers create-virtual-cluster \
    --name "emr-on-eks-cluster-v" \
    --container-provider "{
        \"id\": \"my-eks-cluster\",
        \"type\": \"EKS\",
        \"info\": {
            \"eksInfo\": {
                \"namespace\": \"emr\"
            }
        }
    }"

This configuration makes sure all jobs submitted to this virtual cluster will be deployed in the emr namespace, establishing the foundation for YuniKorn integration.

The YuniKorn interception mechanism

When YuniKorn is installed using Helm, it automatically registers a MutatingAdmissionWebhook with the Kubernetes API server. This webhook acts as an interceptor that monitors pod creation events in your designated namespace. The webhook registration tells Kubernetes to call YuniKorn whenever pods are created in the emr namespace:

# YuniKorn registers this webhook configuration
apiVersion: admissionregistration.k8s.io/v1
kind: MutatingAdmissionWebhook
rules:
- operations: ["CREATE"]
  resources: ["pods"]
  namespaces: ["emr"]  # Intercepts pods in EMR namespace

This webhook is triggered by any pod creation in the emr namespace, not specifically by YuniKorn annotations. However, the webhook’s logic only modifies pods that contain YuniKorn queue annotations, leaving other pods unchanged.

End-to-end job flow

When you submit a Spark job through the Spark Operator, the following sequence occurs:

  1. Your Spark job includes YuniKorn queue annotations on both driver and executor pods:
driver:
  annotations:
    yunikorn.apache.org/queue: "root.analytics-queue"
executor:
  annotations:
    yunikorn.apache.org/queue: "root.analytics-queue"
  1. The Spark Operator processes your SparkApplication and creates individual Kubernetes pods for the driver and executors. These pods inherit the YuniKorn annotations from your job template.
  2. When the Spark Operator attempts to create pods in the emr namespace, Kubernetes calls YuniKorn’s admission webhook. The webhook examines each pod and performs the following actions:
    1. Detects pods with yunikorn.apache.org/queue annotations.
    2. Adds schedulerName: yunikorn to those pods.
    3. Leaves pods without YuniKorn annotations unchanged.

This interception means you don’t need to manually specify schedulerName: yunikorn in your Spark jobs—YuniKorn claims the pods transparently based on the presence of queue annotations.

  1. The YuniKorn scheduler receives the scheduling requests and applies the queue placement rules configured in the YuniKorn ConfigMap:
placementrules:
  - name: provided    # Uses the annotation value
    create: false.    # Doesn’t create the queue if not present
  - name: fixed       # Fallback to root.default queue
    value: root.default

The provided rule reads the yunikorn.apache.org/queue annotation and places the job in the specified queue (for example, root.analytics-queue). YuniKorn then applies gang scheduling logic, holding all pods until sufficient resources are available for the entire application, preventing the partial scheduling issues that come with kube-scheduler.

  1. After YuniKorn determines that all pods can be scheduled according to the queue’s resource guarantees and limits, it schedules all driver and executor pods. The Spark job begins execution with the guaranteed resource allocation defined in the queue configuration.

The combination of namespace-based virtual cluster configuration, admission webhook interception, and annotation-driven queue placement creates an integration that transforms Amazon EMR on EKS job scheduling without disrupting existing workflows.

YuniKorn queue architecture

To demonstrate the various YuniKorn features described in the next section, we configured three job-specific queues and a default queue representing our enterprise teams with carefully balanced resource allocations:

# Analytics Queue - Time-sensitive workloads
analytics-queue:
  guaranteed: 10 vCPUs, 38GB memory (30% of cluster)
  max: 24 vCPUs, 96GB memory (80% burst capacity)
  priority: 100 (highest)
  policy: FIFO (predictable scheduling)
# Marketing Queue - Large batch jobs
marketing-queue:
  guaranteed: 8 vCPUs, 32GB memory (25% of cluster)
  max: 24 vCPUs, 96GB memory (80% burst capacity)
  priority: 75 (medium)
  policy: Fair Share (balanced resource distribution)
# Data Science Queue - Experimental workloads
datascience-queue:
  guaranteed: 6 vCPUs, 26GB memory (20% of cluster)
  max: 24 vCPUs, 96GB memory (80% burst capacity)
  priority: 50 (lower)
  policy: Fair Share (experimental workload balancing)
# Default Queue - Fallback for unmatched jobs
default:
  guaranteed: 6 vCPUs, 26GB memory (20% of cluster)
  max: 24 vCPUs, 96GB memory (80% burst capacity)
  priority: 25 (lowest)
  policy: FIFO (predictable job submission)

Demonstration scenarios

This section outlines key YuniKorn scheduling capabilities and their corresponding Spark job submissions. These scenarios demonstrate guaranteed resource allocation and burst capacity usage. Guaranteed resources represent minimum allocations that queues can always access, but jobs might exceed these allocations when additional cluster capacity is available. The marketing-job specifically demonstrates burst capacity usage beyond its guaranteed allocation.

  • Gang scheduling – In this scenario, we submit analytics-job.py (analytics-queue, 9 total cores) and marketing-job.py (marketing-queue, 17 total cores) simultaneously. YuniKorn makes sure all pods for each job are scheduled atomically, preventing partial resource allocation that could cause job failures in our resource-constrained cluster.
  • Queue-based resource management – We run all three jobs concurrently to observe guaranteed resource allocation. YuniKorn distributes remaining capacity proportionally based on queue weights and maximum limits.
    • analytics-job.py (analytics-queue) receives guaranteed 10 vCPUs and 38 GB memory.
    • marketing-job.py (marketing-queue) receives guaranteed 8 vCPUs and 32 GB memory.
    • datascience-job.py (datascience-queue) receives guaranteed 6 vCPUs and 26 GB memory.
  • Priority-based preemption – We start datascience-job.py (datascience-queue, priority 25) and marketing-job.py (marketing-queue, priority 50) consuming cluster resources, then submit high-priority analytics-job.py (analytics-queue, priority 100). YuniKorn preempts lower-priority jobs to make sure the time-sensitive analytics workload gets its guaranteed resources, maintaining SLA compliance.
  • Fair share distribution – We submit multiple jobs to each queue when all queues have available capacity. YuniKorn applies configured fair share policies within queues—the analytics queue uses First In, First Out (FIFO) method for predictable scheduling, and the marketing and data science queues use fair sharing method for balanced resource distribution.

Source code

You can find the codebase in the AWS Samples GitHub repository.

Prerequisites

Before you deploy this solution, make sure the following prerequisites are in place:

Set up the solution infrastructure

Complete the following steps to set up the infrastructure:

  1. Clone the repository to your local machine and set the two environment variables. Replace <AWS_REGION> with the AWS Region where you want to deploy these resources.
git clone https://github.com/aws-samples/sample-emr-eks-yunikorn-scheduler.git
cd sample-emr-eks-yunikorn-scheduler
export REPO_DIR=$(pwd)
export AWS_REGION=<AWS_REGION>
  1. Execute the following script to create the infrastructure:
cd $REPO_DIR/infrastructure
./setup-infra.sh
  1. To verify successful infrastructure deployment, open the AWS CloudFormation console, choose your stack, and check the Events, Resources, and Outputs tabs for completion status, details, and list of resources created.

Deploy YuniKorn on Amazon EMR on EKS

Run the following script to deploy the Yunikorn helm chart and update the configmap with the queues and placement rules:

cd $REPO_DIR/yunikorn/
./setup-yunikorn.sh

Establish EKS cluster connectivity

Complete the following steps to establish secure connectivity to your private EKS cluster:

  1. Execute the following script in a new terminal window. This script establishes port forwarding through the bastion host to make your private EKS cluster accessible from your local machine. Keep this terminal window open and running throughout your work session. The script maintains the connection to your EKS cluster.
export REPO_DIR=$(pwd)
export AWS_REGION=<AWS_REGION>
cd $REPO_DIR/port-forward
./eks-connect.sh --start
  1. Test kubectl connectivity in the main terminal window to verify that you can successfully communicate with the EKS cluster. You should see the EKS worker nodes listed, confirming that the port forwarding is working correctly.

kubectl get nodes

Verify successful YuniKorn deployment

Complete the following steps to verify a successful deployment:

  1. List all Kubernetes objects in the yunikorn namespace:

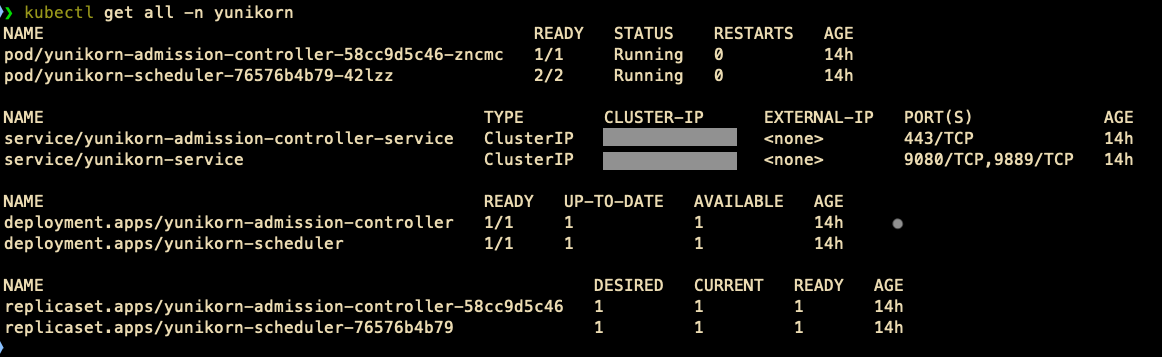
kubectl get all -n yunikorn

You will see details like the following screenshot.

  1. Check the YuniKorn scheduler logs for configuration loading and look for queue configuration messages:
kubectl logs -n yunikorn deployment/yunikorn-scheduler --tail=50
kubectl logs -n yunikorn deployment/yunikorn-scheduler | grep -i queue
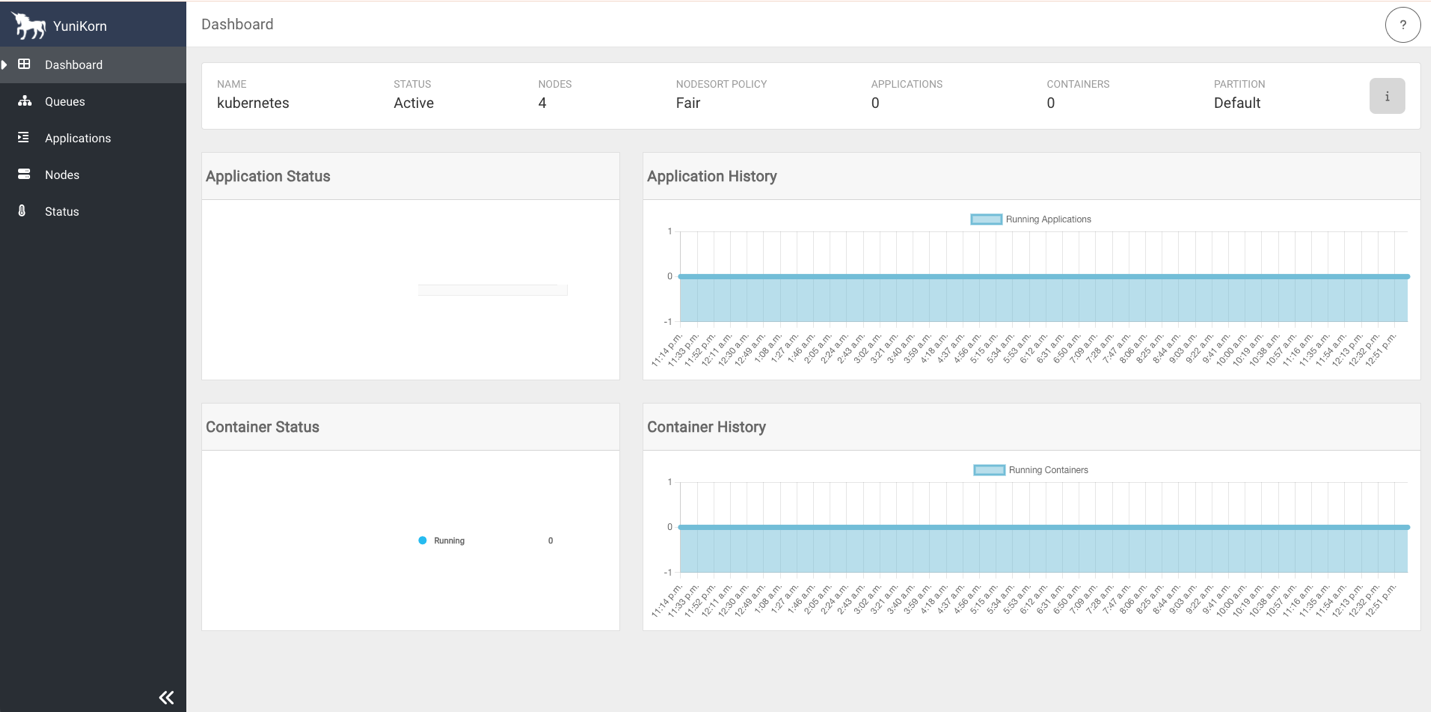
  1. Access the YuniKorn web UI by navigating to http://127.0.0.1:9889 in your browser. Port 9889 is the default port for the YuniKorn web UI.
# macOS
open http://127.0.0.1:9889
# Linux
xdg-open http://127.0.0.1:9889
# Windows
start http://127.0.0.1:9889

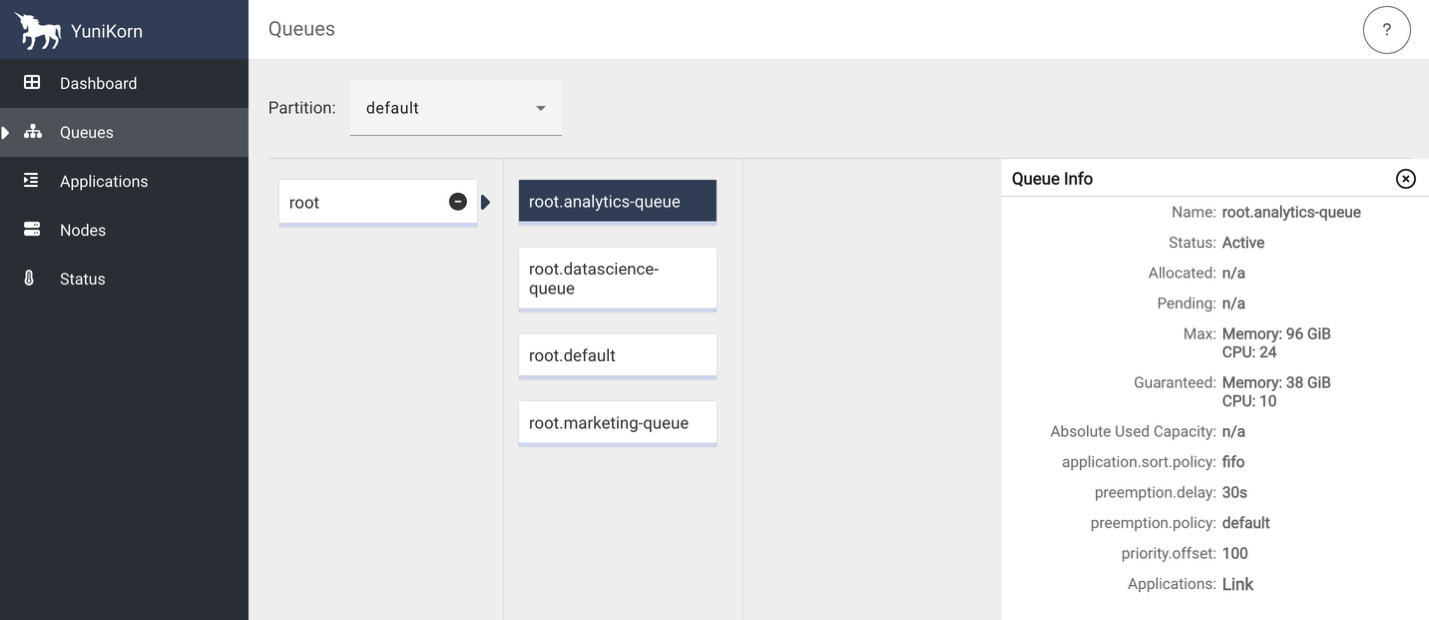
The following screenshots show the YuniKorn web UI with queues but no running applications.

Run Spark jobs with YuniKorn on Amazon EMR on EKS

Complete the following steps to run Spark jobs with YuniKorn on Amazon EMR on EKS:

  1. Execute the following script to set up the Spark jobs environment. The script uploads PySpark scripts to Amazon Simple Storage Service (Amazon S3) bucket locations and creates ready-to-use YAML files from templates.
cd $REPO_DIR/spark-jobs
./setup-spark-jobs.sh
  1. Submit analytics, marketing, and data science Spark jobs using the following commands. YuniKorn will place the jobs in their respective queues and allocate resources to execution. Refer to Using YuniKorn as a custom scheduler for Apache Spark on Amazon EMR on EKS for supported job submission methods with YuniKorn as a custom scheduler.
kubectl apply -f spark-operator/analytics-job.yaml
kubectl apply -f spark-operator/marketing-job.yaml
kubectl apply -f spark-operator/datascience-job.yaml
  1. Review the previous section describing different demonstration scenarios and submit the Spark jobs using various combinations to see YuniKorn scheduler’s capabilities in action. We encourage you to adjust the cores, instances, and memory parameters and explore the scheduler’s behavior by executing the jobs. We also encourage you to modify the queues’ guaranteed and max capacities in the file yunikorn/queue-config-provided.yaml, apply the changes, and submit jobs to further understand Yunikorn scheduler behavior under various circumstances.

Clean up

To avoid incurring future charges, complete the following steps to delete the resources you created:

  1. Stop the port forwarding sessions:
cd $REPO_DIR/port-forwarding
./eks-connect.sh --stop
  1. Remove all created AWS resources:
cd $REPO_DIR
./cleanup.sh

Conclusion

YuniKorn addresses the scheduling limitations of default kube-scheduler while running Spark workloads on Amazon EMR on EKS through gang scheduling, intelligent queue management, and priority-based resource allocation. This post showed how YuniKorn’s queue system enables better resource utilization, prevents job failure due to poor allocation of resources, and supports multi-tenant environments.

To get started with YuniKorn on Amazon EMR on EKS, explore the Apache YuniKorn documentation for implementation guides, review Amazon EMR on EKS best practices for optimization strategies, and engage with the YuniKorn community for ongoing support.


About the authors

Suvojit Dasgupta is a Principal Data Architect at Amazon Web Services. He leads a team of skilled engineers in designing and building scalable data solutions for diverse customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.

Peter Manastyrny is a Senior Product Manager at AWS Analytics. He leads Amazon EMR on EKS, a product that makes it straightforward and efficient to run open-source data analytics frameworks such as Spark on Amazon EKS.

Matt Poland is a Senior Cloud Infrastructure Architect at Amazon Web Services. He is passionate about solving complex problems and delivering well-structured solutions for diverse customers. His expertise spans across a range of cloud technologies, providing scalable and reliable infrastructure tailored to each project’s unique challenges.

Gregory Fina is a Principal Startup Solutions Architect for Generative AI at Amazon Web Services, where he empowers startups to accelerate innovation through cloud adoption. He specializes in application modernization, with a strong focus on serverless architectures, containers, and scalable data storage solutions. He is passionate about using generative AI tools to orchestrate and optimize large-scale Kubernetes deployments, as well as advancing GitOps and DevOps practices for high-velocity teams. Outside of his customer-facing role, Greg actively contributes to open source projects, especially those related to Backstage.
Прозрачност с отпаднала необходимост

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2025/prozrachnost-otpadnala/

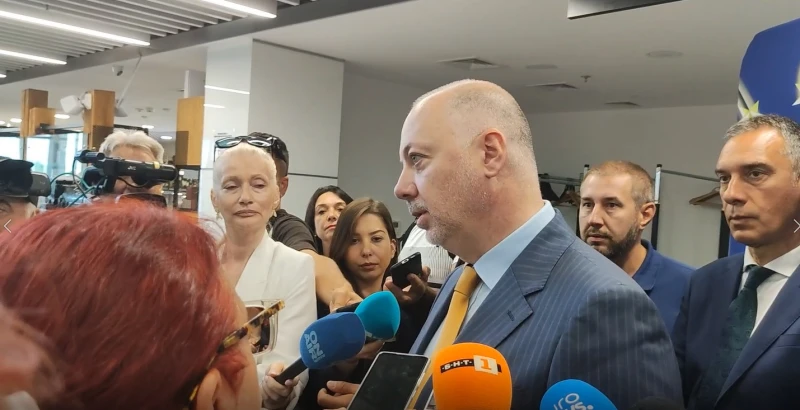
Снимка: Focus

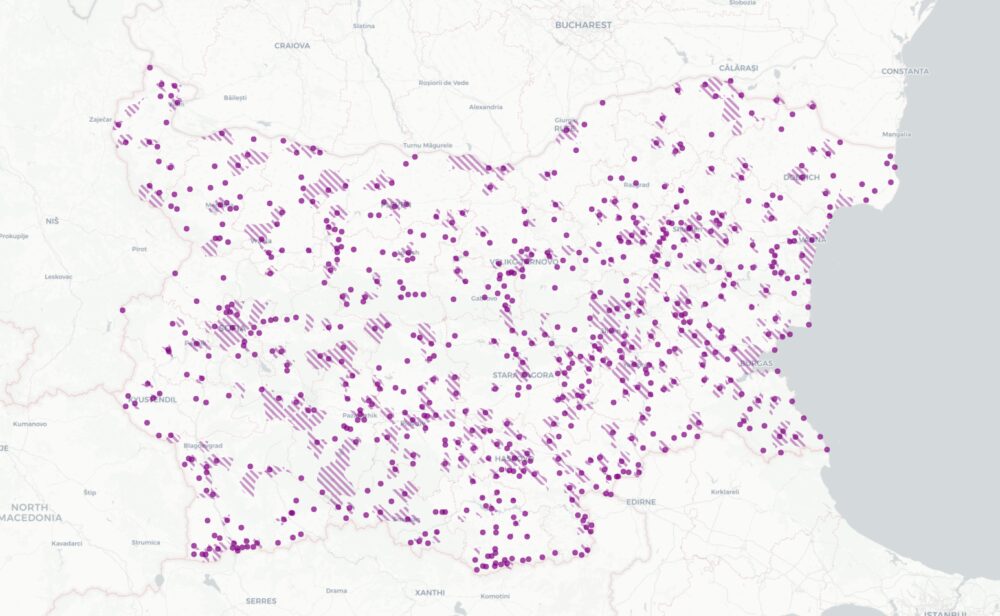
Днес Желязков пред медии се е чудел защо се говори още за онези имоти с отпаднала необходимост. Попитал е дали някой е казал кои са тези имоти. Да, той ми даде списъка и с картата всички разбрахме какви имоти „вече са установени“, както се изрази пред медиите. Всъщност, както стана ясно в последствие, дори той не е знаел кои са всъщност имотите когато са приемали програмата. Медии, общини, а съдейки и по лога на посещенията – самите министерства и областни управи използват моята карта редовно, за да се ориентират какво се случва.

Настоява в изказването си днес, че целта на плана за управление бил да се „систематизира информацията за наличните имоти, да ги опише и за потърси варианти как те да се използват ефективно“. Тук има обаче няколко проблема:

  • програмата сочи към съвсем друго
  • все още не са обяснили какво означава „отпаднала необходимост“ и изглежда ведомствата имат различни идеи за това.
  • в първия списък имаше редица имоти, които всъщност са били продадени години по-рано и не са собственост нито на държавата, нито на държавни фирми
  • скриха първия списък макар да настояваха, че е предварителен и щяло да има анализи за всеки имот
  • нито един анализ за който и да е от имотите, включително тези обявени на търг, не беше публикуван
  • четири месеца по-късно не са публикували нов списък въпреки постоянните обещания, че ще го направят

После пита риторично кой бил казал, че нещо ще се продава. Всъщност, именно той го казва на няколко пъти, пише го в плана и както установих – вече са продадени редица имоти от въпросния списък.

Ето хронологията на твърденията на Желязков заедно с моите статии и отговори към него:

  • 8-ми май – „и разбира се ефективност от тяхната продажба. Продажбата ще се случва през АППК е електронна платформа с явно наддаване… Неизползваеми активи, които генерират разход, но към които има инвестиционен потенциал, следва да бъдат продадени.“ Източник: gov.bg
  • 9-ти май – „Предвижда се част от тях да бъдат продадени, но само тези, които нямат инвестиционен потенциал и са просто актив за държавата.“ Източник: Дневник
  • 10-ти май – Прочит на програмата показва, че най-късно до 30 юни министерства и областни управители трябва да предадат в АППК документи нужни за продажба на имоти. Източник: Сега
  • 27-ми юни – получих от Желязков списъка и направих карта показвайки кои са имотите, които обсъжда.
  • 7-ми юли – намерих първите търгове за имоти от списъка
  • 1-ви август – установих, че МРРБ са изтрили списъка с имоти, които бях получил по ЗДОИ
  • 6-ти август – Парламентът да каже дали да се спира с продажбата на имоти. Твърди, че към дадения момент няма търгове. Източник: gov.bg@Fb
  • 7-ми август – оборих твърдението на Желязков, че няма течащи търгове за имоти от списъка
  • 9-ти август – нови 20 търга, някои с имоти от списъка
  • 26-ти август – изчезна платформата на АППК с търговете заедно с цялата информация за проведените вече такива
  • 2-ри септември – „Просто направихме това, което десетилетия никой не прави – да обяви кои са тези имоти. Някой каза ли кои са тези имоти? Излязоха едни политици и започнаха да лъжат, че нещо се разпродава. Не, систематизира се информацията за наличните имоти.“ Източник: Focus

В самия план за управление думата „продажба“ се споменава 27 пъти в рамките на 10 страници. Една трета – 1466 от 4225 думи са отделени именно на дейности свързани с продажбата. По конкретно се говори за:

  • Страница 4 – „Бързият и прецизен анализ на състоянието на имотите, както и предоставянето на Агенцията за публичните предприятия и контрол (АППК) на тези от тях, които имат висок инвестиционен потенциал за приватизационна продажба, ще осигури постъпления в държавния бюджет. По този начин ще се постигне еднократен ефект, като времевият хоризонт е между 6 м. до 1 година и 6 месеца. Приходите от продажбата на държавно имущество ще постъпват във фонд към министъра на регионалното развитие и благоустройството, създаден със закон.“
  • Цялата точка 4 на страници 5 и 6
  • Страница 8 за исканите промени в ЗДС и ЗПСК, за да се улесни продажбата на имоти на МО
  • Страница 9 и 10 за сроковете за представяне на документи с цел продажба на имотите

Всичко това можеше да бъде избегнато, ако знаеше какво значи прозрачност. Ако думата не беше просто дъвка за замазване на обектива на камерите вперени в него, също както заявката му, че с парите от продажбите на имоти щели да се строят градини и училища. Продажби, за които после беше крайно изнервен, че питаме.

Можеше просто да каже в началото, че цари хаос, че институциите не знаят какви имоти имат и къде са, че шефовете наместени там да обслужват авери на Борисов, Пеевски, Таки и Ковачки и просто са оставили останалото на самотек – също както Сарафов и всички преди него в прокуратурата или сега каквото виждаме в ББР. Можеше да каже, че се цели внасяне на ред и всеки месец ще се публикуват резултатите. Щях да го привествам колкото и зле да беше оформена тази справка. Щях да направя същата карта, за да може ние и те да ги разбираме по-добре също както направи за документите и застрояването на София.

Но прозрачност нямаше. Публикуваха справката с информацията подадена от министерства, областни и държавни фирми. Картата видя бял свят и открихме кои имоти в „най-кратки срокове“ министерствата би следвало да изпратят документация към АППК за търгове. В паниката си скриха този списък и прехвърлиха топката на парламента за пред медиите докато продължаваха с търговете от списъка. В края на август и системата за търговете беше спряна до 12-ти септември без обяснение.

Заявките, че всичко ще е прозрачно не спират, включително днес. Изпратих запитвания по ЗДОИ до АППК и МРРБ. Първите питах какво е причинило спирането на регистъра с търговете. Вторите – да предоставят обновен списък с имоти, които отговарят на дефинициите в плана за управление за имоти, които би следвало да се продават. Всички очакваме отговори на тези въпроси. До днес получавахме само политическо шикалкавене и прехвърляне на топката.

The post Прозрачност с отпаднала необходимост first appeared on Блогът на Юруков.

The impact of the Salesloft Drift breach on Cloudflare and our customers

Post Syndicated from Sourov Zaman original https://blog.cloudflare.com/response-to-salesloft-drift-incident/

Last week, Cloudflare was notified that we (and our customers) are affected by the Salesloft Drift breach. Because of this breach, someone outside Cloudflare got access to our Salesforce instance, which we use for customer support and internal customer case management, and some of the data it contains. Most of this information is customer contact information and basic support case data, but some customer support interactions may reveal information about a customer’s configuration and could contain sensitive information like access tokens. Given that Salesforce support case data contains the contents of support tickets with Cloudflare, any information that a customer may have shared with Cloudflare in our support system—including logs, tokens or passwords—should be considered compromised, and we strongly urge you to rotate any credentials that you may have shared with us through this channel.

As part of our response to this incident, we did our own search through the compromised data to look for tokens or passwords and found 104 Cloudflare API tokens. We have identified no suspicious activity associated with those tokens, but all of these have been rotated in an abundance of caution. All customers whose data was compromised in this breach have been informed directly by Cloudflare.

No Cloudflare services or infrastructure were compromised as a result of this breach.

We are responsible for the choice of tools we use in support of our business. This breach has let our customers down. For that, we sincerely apologize. The rest of this blog gives a detailed timeline and detailed information on how we investigated this breach.

The Salesloft Drift breach

Last week, Cloudflare became aware of suspicious activity within our Salesforce tenant and learned that we, as well as hundreds of other companies, had become the target of a threat actor that was able to successfully exfiltrate the text fields of support cases from our Salesforce instance. Our security team immediately began an investigation, cut off the threat actor’s access, and took a number of steps, detailed below, to secure our environment. We are writing this blog to detail what happened, how we responded, and to help our customers and others understand how to protect themselves from this incident.

Cloudflare uses Salesforce to keep track of who our customers are and how they use our services, and we use it as a support tool to interact with our customers. An important detail to understand as part of this incident is that the threat actor only accessed data in Salesforce “cases,” which may be created when Cloudflare sales and support team members need to comment to each other internally in order to support our customers; they are also created when customers interact with Cloudflare support. Salesforce had an integration with the Salesloft Drift chatbot, which Cloudflare used to give anyone who visited our website a way to contact us.

As Salesloft has announced, a threat actor breached their systems. As part of the breach, the threat actor was able to obtain OAuth credentials associated with the Salesloft Drift chat agent’s Salesforce integration to exfiltrate data from Salesloft customers’ Salesforce instances. Our investigation revealed that this was part of a sophisticated supply chain attack targeting business-to-business third-party integrations, affecting hundreds of organizations globally that were customers of Salesloft. Cloudforce One—Cloudflare’s threat intelligence & research team—has classified the advanced threat actor as GRUB1. Additional disclosures from Google’s Threat Intelligence Group aligned with the activity we observed in our environment.

Our investigation showed the threat actor compromised and exfiltrated data from our Salesforce tenant between August 12-17, 2025, following initial reconnaissance observed on August 9, 2025. A detailed analysis confirmed the exposure was limited to Salesforce case objects, which primarily consist of customer support tickets and their associated data within our Salesforce tenant. These case objects contain customer contact information related to the support case, case subject lines, and the body of the case correspondence—but not any attachments to the cases. Cloudflare does not request or require customers to share secrets, credentials, or API keys in support cases. However, in some troubleshooting scenarios, customers may paste keys, logs, or other sensitive information into the case text fields. Anything shared through this channel should now be considered compromised.

We believe this incident was not an isolated event but that the threat actor intended to harvest credentials and customer information for future attacks. Given that hundreds of organizations were affected through this Drift compromise, we suspect the threat actor will use this information to launch targeted attacks against customers across the affected organizations. 

This post provides a timeline of the attack, details our response, and offers security recommendations to help other organizations mitigate similar threats.

Throughout this blog post, all dates and times are in UTC.

Cloudflare’s response and remediation

When Salesforce and Salesloft notified us on August 23, 2025, that the Drift integration had been abused across multiple organizations, including Cloudflare, we immediately launched a company-wide Security Incident Response. We activated cross-functional teams, pulling together experts from Security, IT, Product, Legal, Communications, and business leadership under a single, unified incident command structure.

We set up four clear priority workstreams with the goal to protect our customers and Cloudflare:

  1. Immediate Threat Containment: We cut off all threat actor access by disabling the compromised Drift integration, conducted forensic analysis to understand the scope of the compromise, and eliminated the active threat from our environment.

  2. Secure our third-party ecosystem: We immediately disconnected all third-party integrations from Salesforce. We issued new secrets for all services and implemented a new process to rotate them weekly.

  3. Safeguard the integrity of our wider systems: We expanded credential rotation to all our third-party Internet services and accounts as a precautionary measure to prevent the attacker from using compromised data to access other Cloudflare systems.

  4. Customer Impact Analysis: We analyzed our Salesforce case objects data to identify whether customers could be compromised and to ensure they received timely and accurate communication about potential exposure.

Attack timeline & Cloudflare response

Our forensic investigation reconstructed the threat actor’s activities against Cloudflare, which occurred between August 9 and August 17, 2025. The following is a chronological summary of the threat actor’s actions, including initial reconnaissance prior to the initial compromise.

August 9, 2025: First signs of reconnaissance

At 11:51, GRUB1 attempted to validate a Customer Cloudflare-issued API token to the Salesforce API. The actor used Trufflehog (a popular open-source secrets scanner) as their User-Agent and sent a verification request to client/v4/user/tokens/verify. The request failed with a 404 Not Found, confirming the token was invalid. The source of this API token is unclear—it could have been obtained from various sources including other Drift customers that GRUB1 may have compromised prior to Cloudflare. 

August 12, 2025: Initial compromise of Cloudflare

At 22:14, GRUB1 gained access to Cloudflare’s Salesforce tenant by using a stolen credential used by the Salesloft integration. Using this credential, the GRUB1 logged in from the IP address 44[.]215[.]108[.]109 and made a GET request to the /services/data/v58.0/sobjects/ API endpoint. This action appeared to enumerate all objects in our Salesforce environment, giving the threat actor a high-level overview of the data stored there.

August 13, 2025: Expanding reconnaissance

One day after the initial breach, the threat actor GRUB1 launched a subsequent attack from the same IP address, 44[.]215[.]108[.]109. Starting at 19:33, the threat actor stole customer data from the Salesforce case objects. They first re-ran an object enumeration to confirm the data structure, then immediately retrieved the case objects’ schema using the /sobjects/Case/describe/ endpoint. This was followed by a broad Salesforce query that enumerated fields from the Salesforce case object.

August 14, 2025: Understanding our Salesforce environment

The threat actor GRUB1 dedicated hours to conduct comprehensive reconnaissance of Cloudflare’s Salesforce tenant from the IP address 44[.]215[.]108[.]109. It appears their objective was to build an understanding of our environment. For several hours, they executed a series of targeted queries:

  • 00:17 – They measured the tenant’s scale by counting accounts, contacts, and users; 

  • 04:34 – Analyzed case workflows by querying CaseTeamMemberHistory; and 

  • 11:09 – Confirmed they were in a production environment by fingerprinting the Organization object. 

The threat actor completed their reconnaissance with additional queries to understand how our customer support system operates—including how team members handle different types of cases, how cases are assigned and escalated, and how our support processes work—and then queried the /limits/ endpoint to learn the API’s operational thresholds. The queries run by GRUB1 provided them with insight into their level of access, the size of the case objects, and the precise API limits they needed to respect to avoid detection within our Salesforce environment.

August 16, 2025: Preparing for the operation

Following the reconnaissance on August 14, 2025, we observed no traffic or successful logins from the threat actor GRUB1 for nearly 48 hours.  

They returned on August 16, 2025. At 19:26, GRUB1 logged back into Cloudflare’s Salesforce tenant from the IP address 44[.]215[.]108[.]109 and, at 19:28, executed a single, final query: SELECT COUNT() FROM Case. This action served as a final “dry run” to verify the exact size of the dataset they were about to steal, marking the definitive end of the reconnaissance phase and setting the stage for the main attack. 

August 17, 2025: Final exfiltration and coverup

GRUB1 initiated the data exfiltration phase by switching to new infrastructure, logging in at 11:11:23 from the IP address 208[.]68[.]36[.]90. After performing one final check on the size of the case object, they launched a Salesforce Bulk API 2.0 job at 11:11:56. In just over three minutes, they successfully exfiltrated a dataset containing the text of support cases—but not any attachments or files—in our instance of Salesforce. At 11:15:42, GRUB1 attempted to cover their tracks by deleting the API job. While this action concealed the primary evidence, our team was able to reconstruct the attack from residual logs. 

We observed no further activity from this threat actor after August 17, 2025.

August 20, 2025: Vendor action ahead of notification

Salesloft revoked Drift-to-Salesforce connections across its customer base and published a notice on their website. At that point, Cloudflare had not yet been notified, and we had no indication that this vendor action might relate to our environment.

August 23, 2025: Salesforce and Salesloft notifications to Cloudflare

Our response to this incident began when Salesforce and Salesloft notified us of unusual Drift-related activity.  We promptly implemented the vendors’ recommended containment steps and engaged them to gather intelligence. 

August 25, 2025: Cloudflare initiates response activity

By August 25, we had received additional intelligence about the incident and escalated our response beyond the initial vendor-recommended containment steps. We launched our own comprehensive investigation and remediation effort.

Our first priority was cutting off GRUB1’s access at the source. We disabled the Drift user account, revoked its client ID and secrets, and completely purged all Salesloft software and browser extensions from Cloudflare systems. This comprehensive removal mitigated the risk of the threat actor reusing compromised tokens, regaining access through stale sessions, or leveraging software extensions for persistence.

Separately, we expanded our security review to include all third-party services connected to our Salesforce environment, rotating credentials as a precautionary measure to prevent any potential lateral movement by the threat actor. 

Since we use Salesforce as our primary tool for managing our customer support data, the risk was that customers had submitted secrets, passwords, or other sensitive data in their customer service requests. We needed to understand what sensitive material the attacker now had. 

We immediately focused on whether any of that data could have been used to compromise our customers accounts, systems, or infrastructure. We examined the data obtained by the threat actor to see if it contained exposed credentials, since cases include freeform text fields where customers may submit Cloudflare API tokens, keys, or logs to our support team. Our teams developed custom scanning tools using regex, entropy, and pattern-matching techniques to detect likely Cloudflare secrets at scale. 

Our investigation confirmed that the exposure was strictly limited to the freeform text in Salesforce case objects—not attachments or files. Cases are used by sales and support teams to communicate internally about customer support issues and to communicate directly with customers. As a result, these case objects contained text-only data consisting of:

  • The subject line of the Salesforce case

  • The body of the case (freeform text which may include any correspondence including keys, secrets, etc., if provided by the customer to Cloudflare)

  • Customer contact information (for example, company name, requestor email address and phone number, company domain name, and company country)

This conclusion was validated through extensive reviews of integrations, authentication activity, endpoint telemetry, and network logs.

August 26–29, 2025: Scaling the response and proactive measures

While the primary Salesforce and Salesloft credentials had already been rotated, our next step was to terminate and securely re-establish our third-party integrations. We began methodically re-onboarding the terminated services, ensuring each was provisioned with new secrets and subject to stricter security controls.

Meanwhile, our teams continued to analyze the data that was exfiltrated. Based on the analysis, we triaged & validated potential exposures, operating under the principle that any data that could have been exposed, was examined. This enabled us to take direct action by rotating Cloudflare platform-issued tokens immediately upon discovery—a total of 104 API tokens were rotated. No suspicious activity has been identified related to those tokens. 

September 2, 2025: Customers notified 

Based on Cloudflare’s detailed analysis—all impacted customers were formally notified via email and banner notices in our Dashboard with information about the incident and recommended next steps. 

Recommendations for all organizations

This incident highlights the critical need for heightened vigilance in securing SaaS applications and other third-party integrations. The data compromised across hundreds of companies targeted in this attack could be used to launch additional attacks. We strongly urge all organizations to adopt the following security measures:

  • Disconnect Salesloft and its applications: Immediately disconnect all Salesloft connections from your Salesforce environment and uninstall any related software or browser extensions.

  • Rotate credentials: Reset the credentials for all third-party applications and integrations connected to your Salesforce instance. Rotate any credentials that may have been previously shared in a support case to Cloudflare. Based on the scope and intent of this attack, we also recommend rotating all third party credentials in your environment as well as any credentials that may have been included in a support case with any other vendor. 

  • Implement frequent credential rotation: Establish a regular rotation schedule for all API keys and other secrets used in your integrations to reduce the window of exposure.

  • Review support case data: Review all customer support case data with your third-party providers to identify what sensitive information may have been exposed. Look for cases containing credentials, API keys, configuration details, or other sensitive data that customers may have shared. For Cloudflare customers specifically: you can access your support case history through the Cloudflare dashboard under Support > Technical Support > My Activities, where you can filter cases or use the “Download Cases” feature to conduct a comprehensive review.

  • Conduct forensics:  Review access logs and permissions to all third-party integrations and review public materials associated with the Drift incident and conduct a security review of your environment as appropriate.

  • Enforce least privilege: Audit all third-party applications to ensure they operate with the minimum level of access (least privilege) required for their function and ensure that admin accounts are not used for vendors. Additionally, enforce strict controls like IP address restrictions and session binding on all third-party and business-to-business (B2B) connections.

  • Enhance monitoring and controls: Deploy enhanced monitoring to detect anomalies such as large data exports or logins from unfamiliar locations. While capturing third party to third party logs can be difficult, it is imperative that these logs are part of your security operations teams.

Indicators of compromise

Below are the Indications of Compromise (IOCs) that we saw from GRUB1. We are publishing them so that other organizations, and especially those that may have been impacted by the Salesloft breach, can search their logs to confirm the same threat actor did not access their systems or third parties.

Indicator

Type

Description

208[.]68[.]36[.]90

IPV4

DigitalOcean based infrastructure 

44[.]215[.]108[.]109

IPV4

AWS based infrastructure 

TruffleHog

User Agent

Open source Secret Scanning tool

Salesforce-Multi-Org-Fetcher/1.0

User Agent

User-Agent string linked to malicious tooling

Salesforce-CLI/1.0

User Agent

Salesforce Command Line Interface (CLI),

python-requests/2.32.4

User Agent

User agent may indicate custom scripting 

Python/3.11 aiohttp/3.12.15

User Agent

User agent which may allow many API calls in parallel

Conclusion

We are responsible for the tools that we select and when those tools are compromised by sophisticated threat actors, we own the consequences. Our team responded to the notice, and our investigation confirmed that the impact was strictly limited to data in Salesforce case objects, with no compromise of other Cloudflare systems or infrastructure.

That said, we consider the compromise of any data to be unacceptable. Our customers trust Cloudflare with their data, their infrastructure, and their security. In turn, we sometimes place our trust in third-party tools which need to be monitored and carefully scoped in what they can access. We are responsible for this. We let our customers down. For this, we sincerely apologize.

As third-party tools increasingly integrate with internal corporate data across the industry, we need to approach each new tool with careful scrutiny. This incident affected hundreds of organizations through a single integration point, highlighting the interconnected risks in today’s technology landscape. We are committed to developing new capabilities to help us and our customers defend against such attacks in the future—stay tuned for announcements during Cloudflare’s Birthday Week later this month.

We are also committed to sharing threat intelligence and research with the broader security community. In the weeks ahead, our Cloudforce One team will publish an in-depth blog analyzing GRUB1’s tradecraft to support the broader community in defending against similar campaigns.

Detailed event timeline

The following table provides a granular, chronological view of GRUB1’s specific actions during the incident.

Date/Time (UTC)

Event Description

2025-08-09 11:51:13

GRUB1 observed leveraging Trufflehog and attempting to verify a token against a Cloudflare Customer Tenant: client/v4/user/tokens/verify, and received a 404 error from 44[.]215[.]108[.]109

2025-08-12 22:14:08

GRUB1 logged into Cloudflare’s Salesforce tenant from 44[.]215[.]108[.]109

2025-08-12 22:14:09

GRUB1 sent a GET request for a list of objects in Cloudflare’s Salesforce tenant: /services/data/v58.0/sobjects/

2025-08-13 19:33:02

GRUB1 logged into Cloudflare’s Salesforce tenant from 44[.]215[.]108[.]109

2025-08-13 19:33:03

GRUB1 sent a GET request for a list of objects in Cloudflare’s Salesforce tenant: /services/data/v58.0/sobjects/

2025-08-13 19:33:07 and 19:33:09

GRUB1 sent a GET request for metadata information for case in Cloudflare’s Salesforce tenant: /services/data/v58.0/sobjects/Case/describe/

2025-08-13 19:33:11

GRUB1 first observed executing Salesforce query: A broad query against the case object by 44[.]215[.]108[.]109. This produced one of the earliest and larger data responses, consistent with reconnaissance via bulk record retrieval

2025-08-14 0:17:40

GRUB1 lists available objects and counts “Account”, “Contact” and “User” objects.

2025-08-14 00:17:47

GRUB1 queried Account table in Cloudflare’s Salesforce tenant: “SELECT COUNT() FROM Account” query on Cloudflare’s Salesforce tenant

2025-08-14 00:17:51

GRUB1 queried Contact table in Cloudflare’s Salesforce tenant: “SELECT COUNT() FROM Contact” query on Cloudflare’s Salesforce tenant

2025-08-14 00:18:00

GRUB1 queried User table in Cloudflare’s Salesforce tenant: “SELECT COUNT() FROM User” query on Cloudflare’s Salesforce tenant

2025-08-14 04:34:39

GRUB1 queried “CaseTeamMemberHistory” in Cloudflare’s Salesforce tenant: “SELECT Id, IsDeleted, Name, CreatedDate, CreatedById, LastModifiedDate, LastModifiedById, SystemModstamp, LastViewedDate, LastReferencedDate, Case__c FROM CaseTeamMemberHistory__c LIMIT 5000”

2025-08-14 11:09:14

GRUB1 queried Organization table in Cloudflare’s Salesforce tenant: “SELECT Id, Name, OrganizationType, InstanceName, IsSandbox FROM Organization LIMIT 1”

2025-08-14 11:09:21

GRUB1 queried User table in Cloudflare’s Salesforce tenant: “SELECT Id, Username, Email, FirstName, LastName, Name, Title, CompanyName, Department, Division, Phone, MobilePhone, IsActive, LastLoginDate, CreatedDate, LastModifiedDate, TimeZoneSidKey, LocaleSidKey, LanguageLocaleKey, EmailEncodingKey FROM User WHERE IsActive = :x ORDER BY LastLoginDate DESC NULLS LAST LIMIT 20”

2025-08-14 11:09:22

GRUB1 sent a GET request on LimitSnapshot in Cloudflare’s Salesforce tenant: /services/data/v58.0/limits/

2025-08-16 19:26:37

GRUB1 logged into Cloudflare’s Salesforce tenant from  44[.]215[.]108[.]109

2025-08-16 19:28:08

GRUB1 queried Cases table in Cloudflare’s Salesforce tenant: SELECT COUNT() FROM Case

2025-08-17 11:11:23

GRUB1 logged into Cloudflare’s Salesforce tenant from 208[.]68[.]36[.]90

2025-08-17 11:11:55

GRUB1 queried Case table in Cloudflare’s Salesforce tenant: SELECT COUNT() FROM Case

2025-08-17 11:11:56 to 11:15:18

GRUB1 leveraged Salesforce BulkAPI 2.0 from 208[.]68[.]36[.]90 to execute a job to exfiltrate the Cases object 

2025-08-17 11:15:42

GRUB1 leveraged Salesforce Bulk API 2.0 from 208[.]68[.]36[.]90 to delete the recently executed job used to exfiltrate the Cases object

Cloud Storage Myths Debunked, Part Four: Managing Multiple Clouds Is Too Complicated

Post Syndicated from David Johnson original https://www.backblaze.com/blog/cloud-storage-myths-debunked-part-four-managing-multiple-clouds-is-too-complicated/

A decorative image showing multiple types of storage media.

Today’s myth feels familiar, because it’s exactly what major cloud providers want you to believe:

Multi-cloud? Sounds like a recipe for chaos. Best stick with one and avoid the hassle.

On the surface, it sounds reasonable. The “big three” clouds promote their all-in-one ecosystems as seamless and unified. One provider, one bill, one console. That should make life easier, right?

Not so fast. The promise of simplicity often hides a different reality: deep complexity, rigid architecture, and vendor lock-in. For many cloud-native teams, what’s pitched as convenience ends up costing time, money, and agility.

This is the final post in our blog series debunking persistent myths about cloud storage. (You can read the first, second, and third articles in the series to get up-to-date.) And, if you’ve ever been told that multi-cloud is messy or risky, this one’s for you.

New Cloud Native Times Call for New Cloud Storage Approaches

Learn more about how the open cloud supports faster development, improved workflows, and reduced cost complexity in our free ebook, “New Cloud Native Times Call for New Cloud Storage Approaches.”

Get the Ebook

Integrated ≠ simple

The idea that one provider equals less overhead is seductive. But in practice, integration can mean entanglement. Instead of reducing operational drag, it creates a tightly woven web of interdependent services and proprietary systems, which makes changes slow and expensive.

The all-in-one trap

Big cloud providers’ platforms are sprawling by design. They’re built to meet every need under one roof. However, the supposed benefit of simplicity falls apart once you actually start using that provider’s full range of services. 

When it comes to storage alone, teams must navigate:

  • Multi-tier systems (hot, cool, cold) with different costs, speeds, and access methods, each requiring its own performance and cost configuration.
  • Complex lifecycle policies and scripts to automate data movement between tiers.
  • Intricate IAM setups to manage roles, policies, and permissions across services.
  • Proprietary APIs and tooling that create migration headaches and limit portability.
  • Console UIs and behaviors that change depending on region or storage class, adding to the learning curve.
  • Deep interdependencies across services, where a small change in storage can ripple through compute, networking, and security layers.

What starts as a unified experience quickly becomes a maze of shifting rules and unstable configurations. And the more deeply your architecture relies on these moving parts, the more frustrating your operations become.

Frustration, not flexibility

Not only is it tedious to manage all of this, but it can be risky. Miss a lifecycle rule, and you might incur unexpected fees. Misconfigure access policies, and you could lose visibility into or even access to your own data.

These aren’t edge cases. They’re everyday realities in cloud-native environments where time is tight, systems are complex, and DevOps teams are stretched thin. Here’s what that might look like in practice:

  • A developer spins up a test environment without realizing data is landing in a high-cost tier.
  • An SRE responds to a latency issue, only to discover the data lives in cold storage and restoring it generates retrieval costs and delays.
  • A backup job fails silently because of a permissions misconfiguration buried deep in nested IAM roles.

And when something breaks, support isn’t always fast or personal. Unless you’re a top-tier customer, you’re likely working through ticketing systems, documentation loops, or community forums.

These moments don’t just cause frustration—they drain time, inflate costs, and hinder your team’s ability to move fast with confidence.

Complexity isn’t a multi-cloud problem. It’s a design problem.

Let’s revisit the myth: Multi-cloud is too complicated.

It’s an understandable concern, but one that’s often based on frustration inside a major cloud provider’s ecosystem. When teams talk about complexity, they’re usually describing the friction that comes from navigating sprawling services, managing brittle configurations, and troubleshooting opaque policies within one provider.

The real issue isn’t how many clouds you use. It’s how much complexity one provider can introduce when you try to adapt, integrate, or scale. Vendor-specific tooling, tightly coupled services, and unpredictable costs create the illusion of simplicity—until you need to do something the platform didn’t anticipate.

That’s not a multi-cloud problem. That’s a design problem.

Making multi-cloud work for you

For many teams, multi-cloud isn’t a grand strategy, but something that happens organically. AI workloads move to GPU providers. Content gets delivered through specialized CDNs. Backups shift to more cost-effective and geographically separated storage. Whether by design or necessity, most modern architectures already span multiple clouds.

So the smarter question isn’t “Should we avoid it?” It’s “How do we make it sustainable without adding unnecessary complexity?”

That’s where Backblaze B2 comes in.

Backblaze B2 is purpose-built to make multi-cloud not only possible, but practical—for DevOps, SREs, and developers alike. It’s focused, interoperable, and refreshingly straightforward:

  • Always-hot storage: No tier juggling. No lifecycle scripts. Just fast, consistent access.
  • S3-compatible APIs: Seamlessly integrates with the tools and platforms you already use, such as Terraform, Kubernetes, ArgoCD, boto3, and more.
  • Streamlined IAM and UI: Control access and monitor usage without wading through layers of enterprise-grade configuration.
  • Free egress: Move data where you need it and when you need to, without the surprise charges that make multi-cloud cost-prohibitive.

Many teams start small with offloading archives, mirroring backup buckets, or feeding GPU pipelines for AI training. As modular architectures grow, Backblaze B2 scales with them, but without the rigidity or lock-in.

In fact, a 2025 Enterprise Strategy Group study found that many operational tasks, such as storage deployments, storage management, and integration with the hardware and software that they already used took up to 92% less time.

The simple interface contrasted sharply with other Cloud Service Providers’ interfaces that have confusing navigation and multiple options to sort through.

—Enterprise Strategy Group, “Analyzing the Economic Benefits of the Backblaze B2 Cloud Storage Platform,” May 2025.

Multi-cloud doesn’t have to be messy. With the right storage layer, it becomes your cleanest, most strategic advantage.

Want to dig even deeper?

Download the full ebook New Cloud-Native Times Call for New Cloud Storage Approaches to explore how modular, interoperable strategies are changing the cloud-native game.

The post Cloud Storage Myths Debunked, Part Four: Managing Multiple Clouds Is Too Complicated appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

[$] Removing Guix from Debian

Post Syndicated from jzb original https://lwn.net/Articles/1035491/

As a rule, if a package is shipped with a Debian release, users can
count on it being available, and updated, for the entire
life of the release. If package foo is included in the stable
release—currently Debian 13
(“trixie”)—a user can
reasonably expect that it will continue to be available with security
backports as long as that release is supported, though it may not be
included in Debian 14 (“forky”). However, it is likely that the
Guix package manager will soon
be removed from the repositories for Debian 13 and
Debian 12 (“bookworm”, also called oldstable).

The hidden vulnerabilities of open source (FastCode)

Post Syndicated from corbet original https://lwn.net/Articles/1036373/

The FastCode site has a
lengthy article
on how large language models make open-source projects
far more vulnerable to XZ-style attacks.

Open source maintainers, already overwhelmed by legitimate
contributions, have no realistic way to counter this threat. How do
you verify that a helpful contributor with months of solid commits
isn’t an LLM generated persona? How do you distinguish between
genuine community feedback and AI created pressure campaigns? The
same tools that make these attacks possible are largely
inaccessible to volunteer maintainers. They lack the resources,
skills, or time to deploy defensive processes and systems.

The detection problem becomes exponentially harder when LLMs can
generate code that passes all existing security reviews,
contribution histories that look perfectly normal, and social
interactions that feel authentically human. Traditional code
analysis tools will struggle against LLM generated backdoors
designed specifically to evade detection. Meanwhile, the human
intuition that spot social engineering attacks becomes useless when
the “humans” are actually sophisticated language models.

Security updates for Tuesday

Post Syndicated from corbet original https://lwn.net/Articles/1036369/

Security updates have been issued by AlmaLinux (kernel, mod_http2, postgresql, postgresql:15, and python39:3.9), Debian (libsndfile), Mageia (ceph, glibc, and golang), Oracle (postgresql and python39:3.9), Red Hat (aide, postgresql:12, postgresql:13, postgresql:15, and postgresql:16), SUSE (git, govulncheck-vulndb, jetty-minimal, nginx, python-future, and ruby2.5), and Ubuntu (imagemagick).

Anthropomorphization Cedes Ground to Artificial Intelligence & LLM Ballyhoo

Post Syndicated from Bradley M. Kuhn original http://ebb.org/bkuhn/blog/2025/09/02/ai-llm-hallucination-ballyhoo.html

Big Tech seeks every advantage to convince users that computing is
revolutionized by the latest fad. When the tipping point of Large
Language Models (LLMs) was reached a few years ago,
generative Artificial Intelligence (AI) systems quickly
became that latest snake oil for sale on the carnival podium.

There’s so much to criticize about generative AI, but I focus now merely on the
pseudo-scientific rhetoric adopted to describe the LLM-backed
user-interactive systems in common use today. “Ugh, what a
convoluted phrase”, you may ask, “why not call them
‘chat bots’ like everyone else?” Because “chat
bot” exemplifies the very anthropomorphic hyperbole of
concern.

Too often, software freedom activists (including me — 😬) have asked us to
police our language as an advocacy tactic. Herein, I seek not to cajole everyone
to end AI anthropomorphism. I suggest rather that, when you
write about the latest Big Tech craze, ask yourself: Is my
rhetoric actually reinforcing the message of the very bad actors that I
seek to criticize?

This work now has interested parities with varied motivations. Researchers, for example,
will usually
admit that
they have nothing to contribute to philosophical debates about whether it is
appropriate to … [anthropomorphize] … machines
. But
researchers also can never resist a nascent area of study — so all
the academic disclaimers do not prevent the “world of
tomorrow” exuberance
expressed
by those
whose work is now the flavor of the month (especially after they toiled at it for
decades in relative obscurity). Computer science (CS)
academics are too closely tied to the Big Tech gravy train even in mundane
times. But when the VCs
stand on their disruptor soap-boxes and make it rain 💸? … Some corners of CS
academia do become a capitalist echo chamber.

The research behind these LLM-backed generative AI systems is (mostly) not
actually new. There’s just more electricity, CPUs/GPUs, & digital data available now. When given
ungodly resources, well-known techniques began yielding novel results. That allowed for quicker incremental (not exponential) improvement. But, a revolution it is not.

I once asked a fellow CS graduate student (in the mid-1990s), who was
presenting their neural net — built with DoD funding to spot tanks behind
trees —, the simple question0: Do you know why it’s wrong when
it’s wrong and why it’s right when it’s right?
. She grimaced and
answered: Not at all. It doesn’t think.. 30 years later, machines still don’t think.

Precisely there lies the danger of anthropomorphization. While we may never
know why our fellow humans believe what they believe —
after centuries that brought1 Heraclitus, Aristotle, Aquinas, Bacon,
Decartes, Kant, Kierkegaard, and Haack — we do know that people think, and therefore,
they are. Computers aren’t.
Software isn’t. When we who are succumb to the capitalist chicanery
and erroneously projected being unto these systems, we take our first step toward
relinquishing our inherent power over these systems.

Counter-intuitively, the most dangerous are the AI anthropomorphism that criticize rather
than laud the systems. The worst of these, “hallucination”, is
insidious. Appropriation of a
diagnostic term from the DSM-5 into CS literature is abhorrent — prima facie . The term
leads the reader to the Bizarro world where programmers are doctors who
heal sick programs for the betterment of society. Annoyingly and
ironically — even if we did wish to anthropomorphize — LLM-backed generative AI systems almost never
hallucinate. If one were to insist on lifting an analogous term from mental illness diagnosis
(which I obviously don’t recommend), the term is “delusional”.
Frankly, having spent hundreds of hours of my life talking with a mentally
ill family member who is frequently delusional but has almost never
hallucinated — and having to learn to delineate the two for the
purpose of assisting in the individual’s care — I find it downright
offensive and triggering that either term could possibly be used to
describe a thing rather than a person.

Sadly, Big Tech really wants us to jump (not walk) to the conclusion that these systems
are human — or, at least, as beloved pets that we can’t
imagine living without. Critics like me are easily framed as Luddites
when we’ve been socially manipulated into viewing — as “almost
human” — these machines poised to replace the artisans, the law enforcers, and the grocery stockers. Like many of you, I read
Asimov as a child. I later cheered during ST:TNG S02E09 (“Measure of a
Man”) when Lawyer Picard established Mr. Data’s right to sentience
by shouting:
Your Honour, Starfleet was founded to seek out new life. Well, there it
sits.
But, I assure you as someone who has devoted much of my life to
considering the moral and ethical implication of Big Tech: they have
yet to give us Mr. Data — and if they eventually do, that Mr. Data2
is
probably going to work for ICE, not Starfleet. Remember, Noonien Soong’s
fictional positronic opus was altruistic only because Soong worked in a post-scarcity society.

While I was still working on a draft of this
essay, Eryk
Salvaggio’s essay “Human Literacy” was published
.
Salvaggio makes excellent further reading on the points above.

🎶


Footnotes:

0I always find that, in science, the answers simplest questions are always
the most illuminating. I’m reminded how Clifford Stoll wrote about the
most pertinent question at his PhD Physics prelims was “why is the
sky blue?”.

1I
really just picked a list of my favorite epistemologists here that sounded
good when stated in a row; I apologize in advance if I left out your
favorite from the list.

2I realize fellow
Star Trek fans will say I was moving my lips and nothing came out but a
bunch of gibberish because I forgot about Lore. 😛 I didn’t forget about
Lore; that, my readers, would have to be a topic for a different blog
post.

The collective thoughts of the interwebz