Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=ScoJuxjdTgE
[$] LWN.net Weekly Edition for September 4, 2025
Post Syndicated from corbet original https://lwn.net/Articles/1035384/
Inside this week’s LWN.net Weekly Edition:
- Front: Maintaining curl; GNOME governance; Guix in Debian; Tracking untrusted data in the kernel; 32-Bit support; systemd v258.
- Briefs: bcachefs maintenance; Linux from Scratch 12.4; Elf spec; Niri 25.08; Python documentary; GNOME executive director; Quotes; …
- Announcements: Newsletters, conferences, security updates, patches, and more.
That’s a Lot of Birds
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/-UzxxHEFPoA
Intel Arc Pro B50 Review A 16GB SFF Mini GPU
Post Syndicated from John Lee original https://www.servethehome.com/intel-arc-pro-b50-review-a-16gb-sff-mini-gpu/
In our Intel Arc Pro B50 review, we see how Intel succeeded in making a really attractive 16GB low-profile and quiet GPU at only $349 list
The post Intel Arc Pro B50 Review A 16GB SFF Mini GPU appeared first on ServeTheHome.
Deep dive into the Amazon Managed Service for Apache Fink application lifecycle – Part 2
Post Syndicated from Lorenzo Nicora original https://aws.amazon.com/blogs/big-data/part-2-deep-dive-into-the-amazon-managed-service-for-apache-fink-application-lifecycle/
In Part 1 of this series, we discussed fundamental operations to control the lifecycle of your Amazon Managed Service for Apache Flink application. If you are using higher-level tools such as AWS CloudFormation or Terraform, the tool will execute these operations for you. However, understanding the fundamental operations and what the service automatically does can provide some level of Mechanical Sympathy to confidently implement a more robust automation.
In the first part of this series, we focused on the happy paths. In an ideal world, failures don’t happen, and every change you deploy works perfectly. However, the real world is less predictable. Quoting Werner Vogels, Amazon’s CTO, “Everything fails, all the time.”
In this post, we explore failure scenarios that can happen during normal operations or when you deploy a change or scale the application, and how to monitor operations to detect and recover when something goes wrong.
The less happy path
A robust automation must be designed to handle failure scenarios, in particular during operations. To do that, we need to understand how Apache Flink can deviate from the happy path. Due to the nature of Flink as a stateful stream processing engine, detecting and resolving failure scenarios requires different techniques compared to other long-running applications, such as microservices or short-lived serverless functions (such as AWS Lambda).
Flink’s behavior on runtime errors: The fail-and-restart loop
When a Flink job encounters an unexpected error at runtime (an unhandled exception), the normal behavior is to fail, stop the processing, and restart from the latest checkpoint. Checkpoints allow Flink to support data consistency and no data loss in case of failure. Also, because Flink is designed for stream processing applications, which run continuously, if the error happens again, the default behavior is to keep restarting, hoping the problem is transient and the application will eventually recover the normal processing.In some cases, the problem is not transient, however. For example, when you deploy a code change that contains a bug, causing the job to fail as soon as it starts processing data, or if the expected schema doesn’t match the records in the source, causing deserialization or processing errors. The same scenario might also happen if you mistakenly changed a configuration that prevents a connector to reach the external system. In these cases, the job is stuck in a fail-and-restart loop, indefinitely, or until you actively force-stop it.
When this happens, the Managed Service for Apache Flink application status might be RUNNING, but the underlying Flink job is actually failing and restarting. The AWS Management Console gives you a hint, pointing that the application might need attention (see the following screenshot).
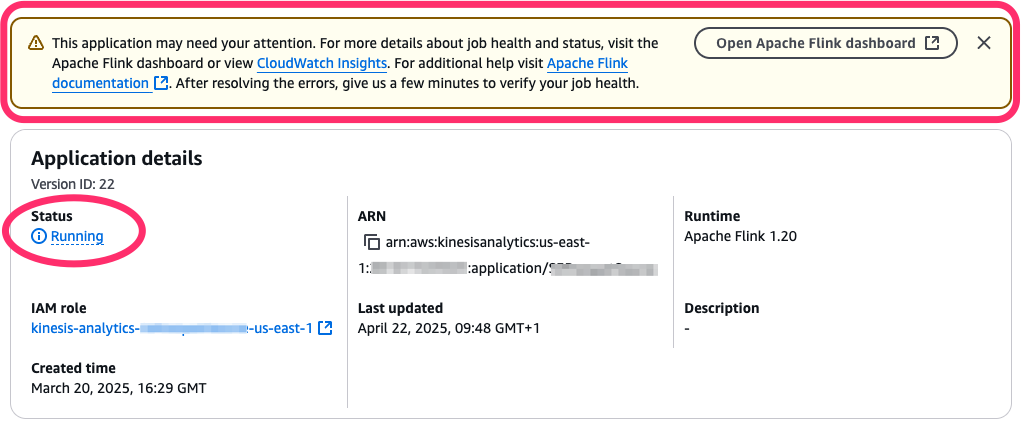
In the following sections, we learn how to monitor the application and job status, to automatically react to this situation.
When starting or updating the application goes wrong
To understand the failure mode, let’s review what happens automatically when you start the application, or when the application restarts after you issued UpdateApplication command, as we explored in Part 1 of this series. The following diagram illustrates what happens when an application starts.
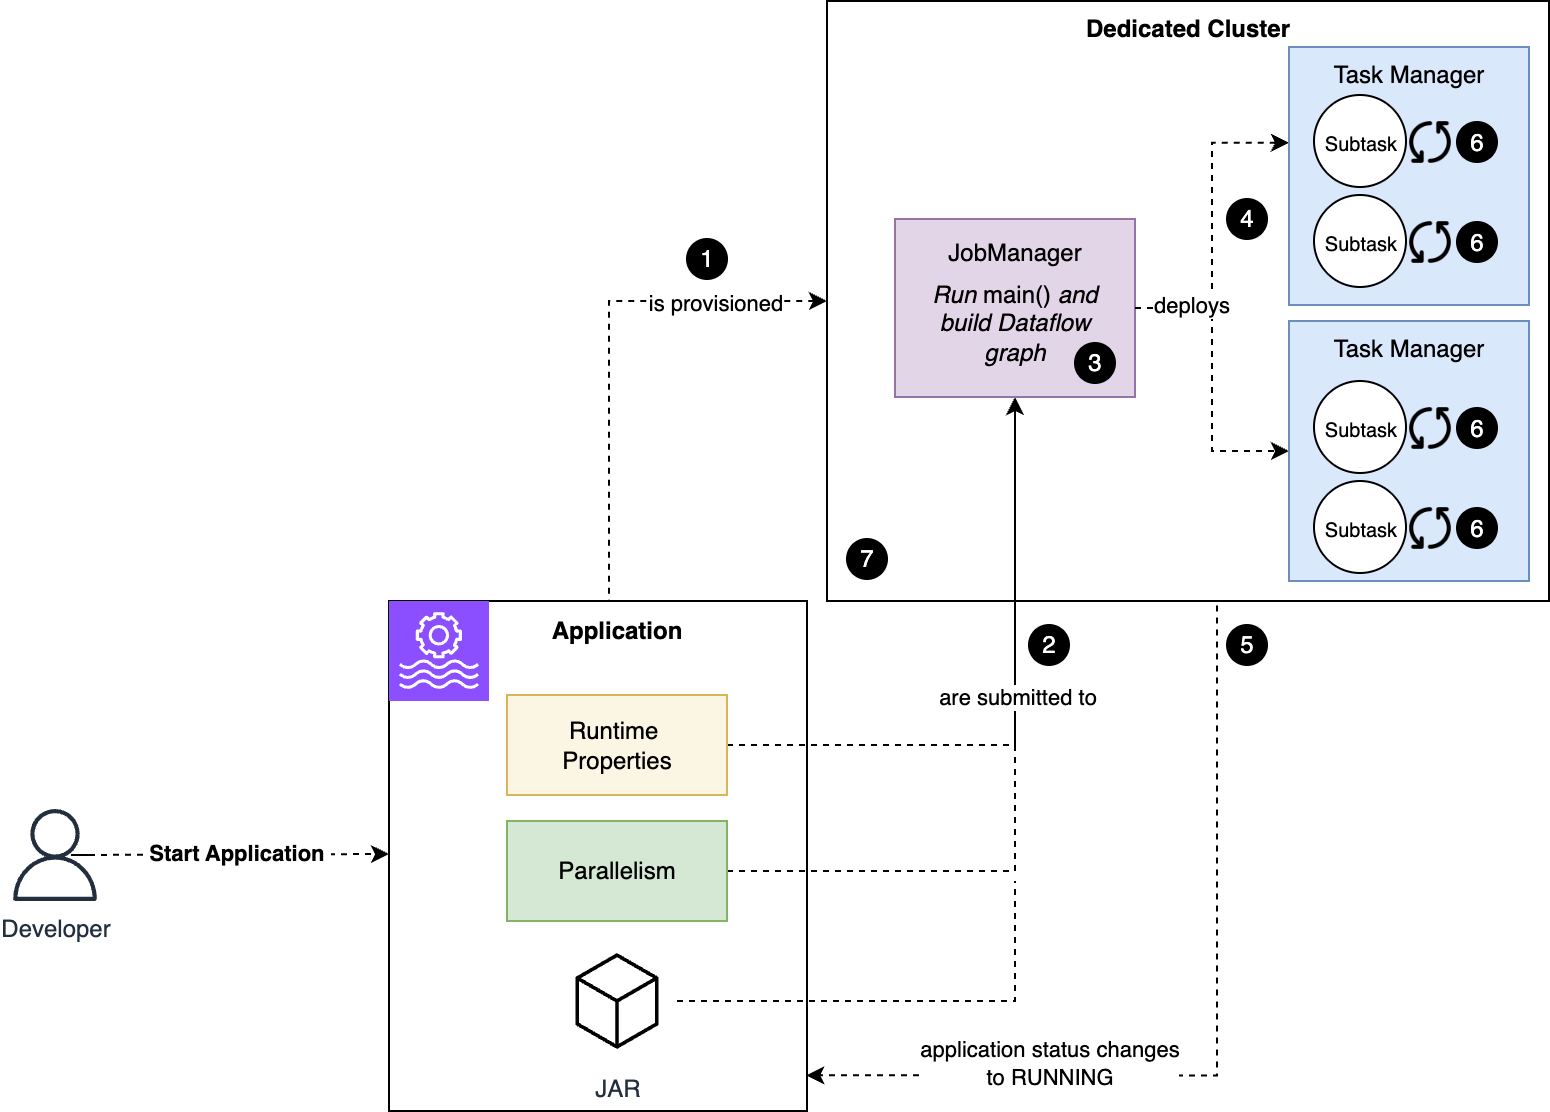
The workflow consists of the following steps:
- Managed Service for Apache Flink provisions a cluster dedicated to your application.
- The code and configuration are submitted to the Job Manager node.
- The code in the
main()method of your application runs, defining the dataflow of your application. - Flink deploys to the Task Manager nodes the substasks that make up your job.
- The job and application status change to
RUNNING. However, subtasks start initializing now. - Subtasks restore their state, if applicable, and initialize any resources. For example, a Kafka connector’s subtask initializes the Kafka client and subscribes the topic.
- When all subtasks are successfully initialized, they change to
RUNNINGstatus and the job starts processing data.
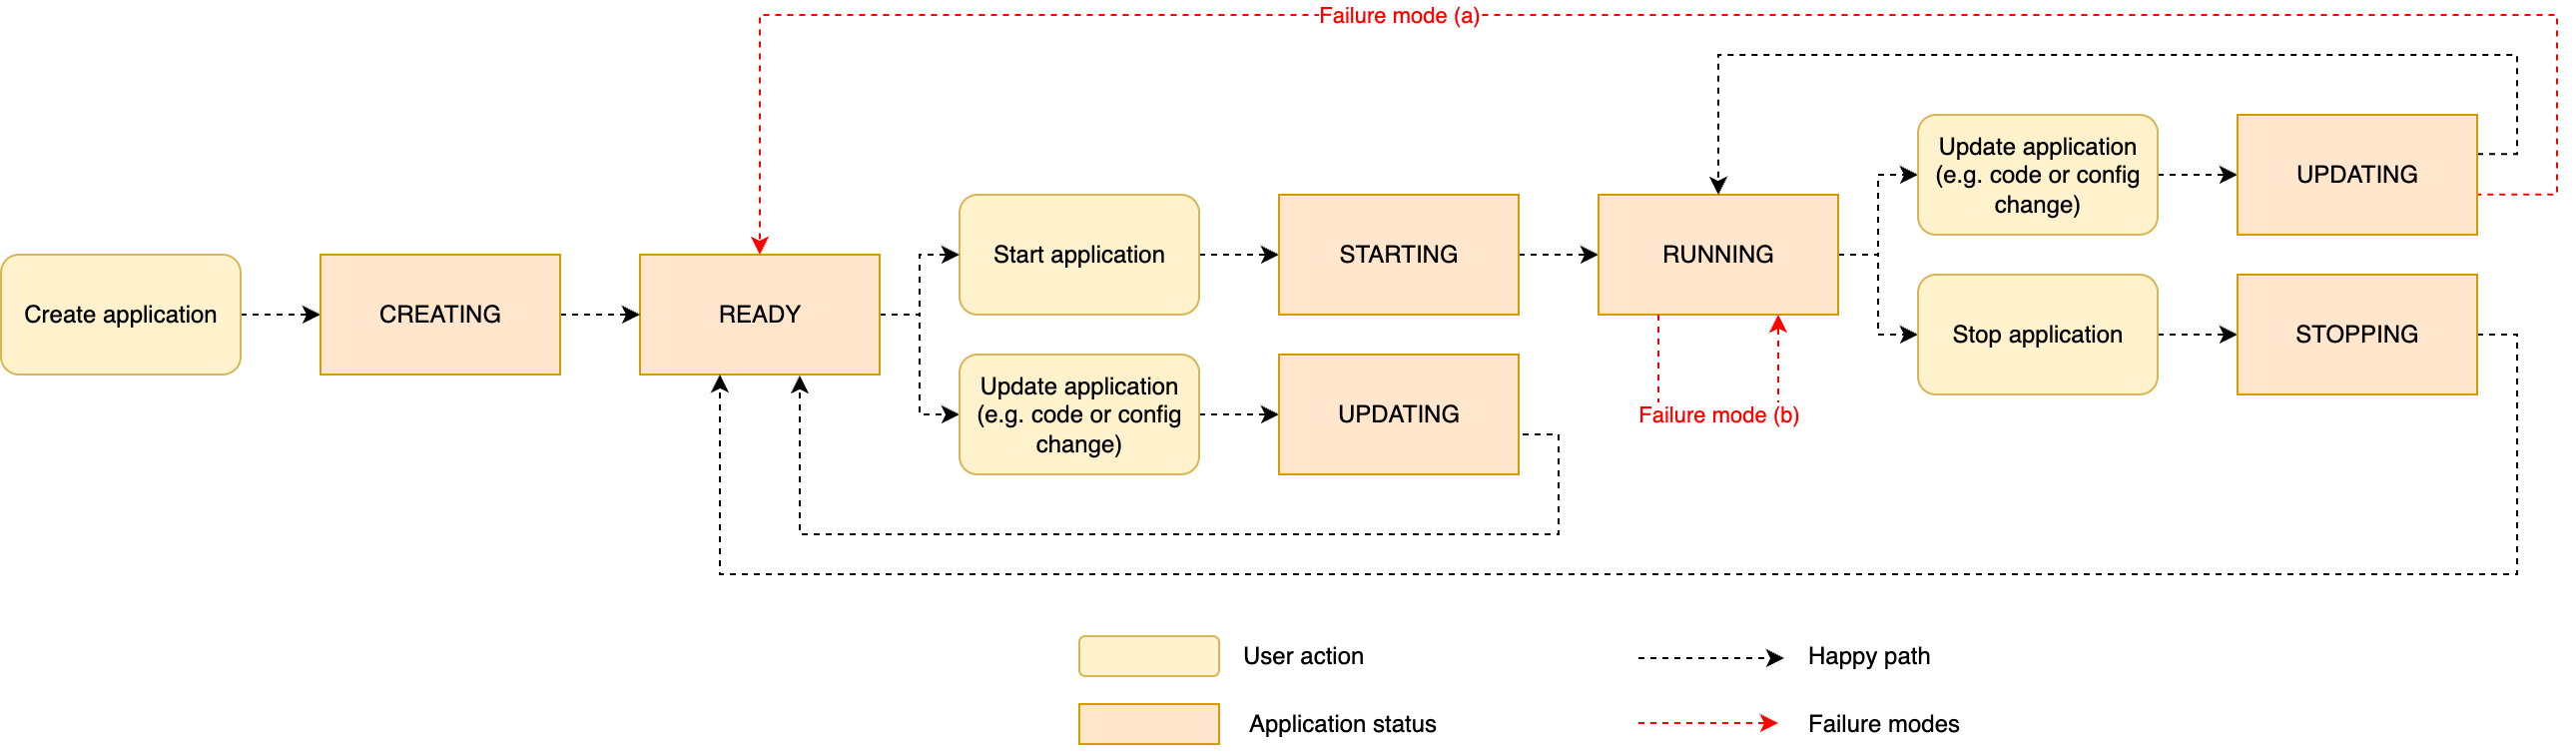
To new Flink users, it can be confusing that a RUNNING status doesn’t necessarily imply the job is healthy and processing data.When something goes wrong during the process of starting (or restarting) the application, depending on the phase when the problem arises, you might observe two different types of failure modes:
- (a) A problem prevents the application code from being deployed – Your application might encounter this failure scenario if the deployment fails as soon as the code and configuration are passed to the Job Manager (step 2 of the process), for example if the application code package is malformed. A typical error is when the JAR is missing a
mainClassor ifmainClasspoints to a class that doesn’t exist. This failure mode might also happen if the code of yourmain()method throws an unhandled exception (step 3). In these cases, the application fails to change toRUNNING, and reverts toREADYafter the attempt. - (b) The application is started, the job is stuck in a fail-and-restart loop – A problem might occur later in the process, after the application status has changed
RUNNING. For example, after the Flink job has been deployed to the cluster (step 4 of the process), a component might fail to initialize (step 6). This might happen when a connector is misconfigured, or a problem prevents it from connecting to the external system. For example, a Kafka connector might fail to connect to the Kafka cluster because of the connector’s misconfiguration or networking issues. Another possible scenario is when the Flink job successfully initializes, but it throws an exception as soon as it starts processing data (step 7). When this happens, Flink reacts to a runtime error and might get stuck in a fail-and-restart loop.
The following diagram illustrates the sequence of application status, including the two failure scenarios just described.
Troubleshooting
We have examined what can go wrong during operations, in particular when you update a RUNNING application or restart an application after changing its configuration. In this section, we explore how we can act on these failure scenarios.
Roll back a change
When you deploy a change and realize something is not quite right, you normally want to roll back the change and put the application back in working order, until you investigate and fix the problem. Managed Service for Apache Flink provides a graceful way to revert (roll back) a change, also restarting the processing from the point it was stopped before applying the fault change, providing consistency and no data loss.In Managed Service for Apache Flink, there are two types of rollbacks:
- Automatic – During an automatic rollback (also called system rollback), if enabled, the service automatically detects when the application fails to restart after a change, or when the job starts but immediately falls into a fail-and-restart loop. In these situations, the rollback process automatically restores the application configuration version before the last change was applied and restarts the application from the snapshot taken when the change was deployed. See Improve the resilience of Amazon Managed Service for Apache Flink application with system-rollback feature for more details. This feature is disabled by default. You can enable it as part of the application configuration.
- Manual – A manual rollback API operation is like a system rollback, but it’s initiated by the user. If the application is running but you observe something not behaving as expected after applying a change, you can trigger the rollback operation using the RollbackApplication API action or the console. Manual rollback is possible when the application is
RUNNINGorUPDATING.
Both rollbacks work similarly, restoring the configuration version before the change and restarting with the snapshot taken before the change. This prevents data loss and brings you back to a version of the application that was working. Also, this uses the code package that was saved at the time you created the previous configuration version (the one you are rolling back to), so there is no inconsistency between code, configuration, and snapshot, even if in the meantime you have replaced or deleted the code package from the Amazon Simple Storage Service (Amazon S3) bucket.
Implicit rollback: Update with an older configuration
A third way to roll back a change is to simply update the configuration, bringing it back to what it was before the last change. This creates a new configuration version, and requires the correct version of the code package to be available in the S3 bucket when you issue the UpdateApplication command.
Why is there a third option when the service provides system rollback and the managed RollbackApplication action? Because most high-level infrastructure-as-code (IaC) frameworks such as Terraform use this strategy, explicitly overwriting the configuration. It is important to understand this possibility even though you will probably use the managed rollback if you implement your automation based on the low-level actions.
The following are two important caveats to consider for this implicit rollback:
- You will normally want to restart the application from the snapshot that was taken before the faulty change was deployed. If the application is currently
RUNNINGand healthy, this is not the latest snapshot (RESTORE_FROM_LATEST_SNAPSHOT), but rather the previous one. You must set the restart fromRESTORE_FROM_CUSTOM_SNAPSHOTand select the correct snapshot. - UpdateApplication only works if the application is
RUNNINGand healthy, and the job can be gracefully stopped with a snapshot. Conversely, if the application is stuck in a fail-and-restart loop, you must force-stop it first, change the configuration while the application isREADY, and later start the application from the snapshot that was taken before the faulty change was deployed.
Force-stop the application
In normal scenarios, you stop the application gracefully, with the automatic snapshot creation. However, this might not be possible in some scenarios, such as if the Flink job is stuck in a fail-and-restart loop. This might happen, for example, if an external system the job uses stops working, or because the AWS Identity and Access Management (IAM) configuration was erroneously modified, removing permissions required by the job.
When the Flink job gets stuck in a fail-and-restart loop after a faulty change, your first option should be using RollbackApplication, which automatically restores the previous configuration and starts from the correct snapshot. In the rare cases you can’t stop the application gracefully or use RollbackApplication, the last resort is force-stopping the application. Force-stop uses the StopApplication command with Force=true. You can also force-stop the application from the console.
When you force-stop an application, no snapshot is taken (if that were possible, you would have been able to gracefully stop). When you restart the application, you can either skip restoring from a snapshot (SKIP_RESTORE_FROM_SNAPSHOT) or use a snapshot that was previously taken, scheduled using Snapshot Manager, or manually, using the console or CreateApplicationSnapshot API action.
We strongly recommend setting up scheduled snapshots for all production applications that you can’t afford restarting with no state.
Monitoring Apache Flink application operations
Effective monitoring of your Apache Flink applications during and after operations is crucial to verify the outcome of the operation and allow lifecycle automation to raise alarms or react, in case something goes wrong.
The main indicators you can use during operations include the FullRestarts metric (available in Amazon CloudWatch) and the application, job, and task status.
Monitoring the outcome of an operation
The simplest way to detect the outcome of an operation, such as StartApplication or UpdateApplication, is to use the ListApplicationOperations API command. This command returns a list of the most recent operations of a specific application, including maintenance events that force an application restart.
For example, to retrieve the status of the most recent operation, you can use the following command:
The output will be similar to the following code:
OperationStatus will follow the same logic as the application status reported by the console and by DescribeApplication. This means it might not detect a failure during the operator initialization or while the job starts processing data. As we have learned, these failures might put the application in a fail-and-restart loop. To detect these scenarios using your automation, you must use other techniques, which we cover in the rest of this section.
Detecting the fail-and-restart loop using the FullRestarts metric
The simplest way to detect whether the application is stuck in a fail-and-restart loop is using the fullRestarts metric, available in CloudWatch Metrics. This metric counts the number of restarts of the Flink job after you started the application with a StartApplication command or restarted with UpdateApplication.
In a healthy application, the number of full restarts should ideally be zero. A single full restart might be acceptable during deployment or planned maintenance; multiple restarts normally indicate some issue. We recommend not to trigger an alarm on a single restart, or even a couple of consecutive restarts.
The alarm should only be triggered when the application is stuck in a fail-and-restart loop. This implies checking whether several restarts have happened over a relatively short period of time. Deciding the period is not trivial, because the time the Flink job takes to restart from a checkpoint depends on the size of the application state. However, if the state of your application is lower than several GB per KPU, you can safely assume the application should start in less than a minute.
The goal is creating a CloudWatch alarm that triggers when fullRestarts keeps increasing over a time period sufficient for multiple restarts. For example, assuming your application restarts in less than 1 minute, you can create a CloudWatch alarm that relies on the DIFF math expression of the fullRestarts metric. The following screenshot shows an example of the alarm details.
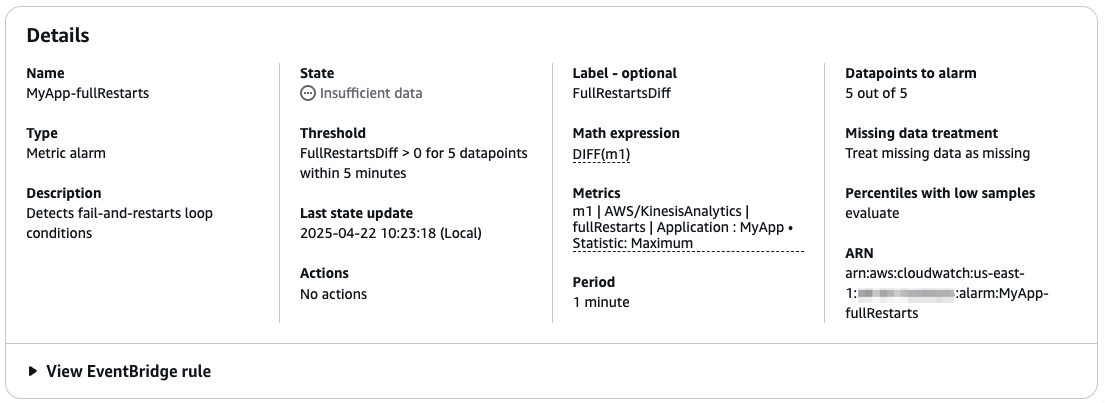
This example is a conservative alarm, only triggering if the application keeps restarting for over 5 minutes. This means you detect the problem after at least 5 minutes. You might consider reducing the time to detect the failure earlier. However, be careful not to trigger an alarm after just one or two restarts. Occasional restarts might happen, for example during normal maintenance (patching) that is managed by the service, or for a transient error of an external system. Flink is designed to recover from these conditions with minimal downtime and no data loss.
Detecting whether the job is up and running: Monitoring application, job, and task status
We have discussed how you have different statuses: the status of the application, job, and subtask. In Managed Service for Apache Flink, the application and job status change to RUNNING when the subtasks are successfully deployed on the cluster. However, the job is not really running and processing data until all the subtasks are RUNNING.
Observing the application status during operations
The application status is visible on the console, as shown in the following screenshot.
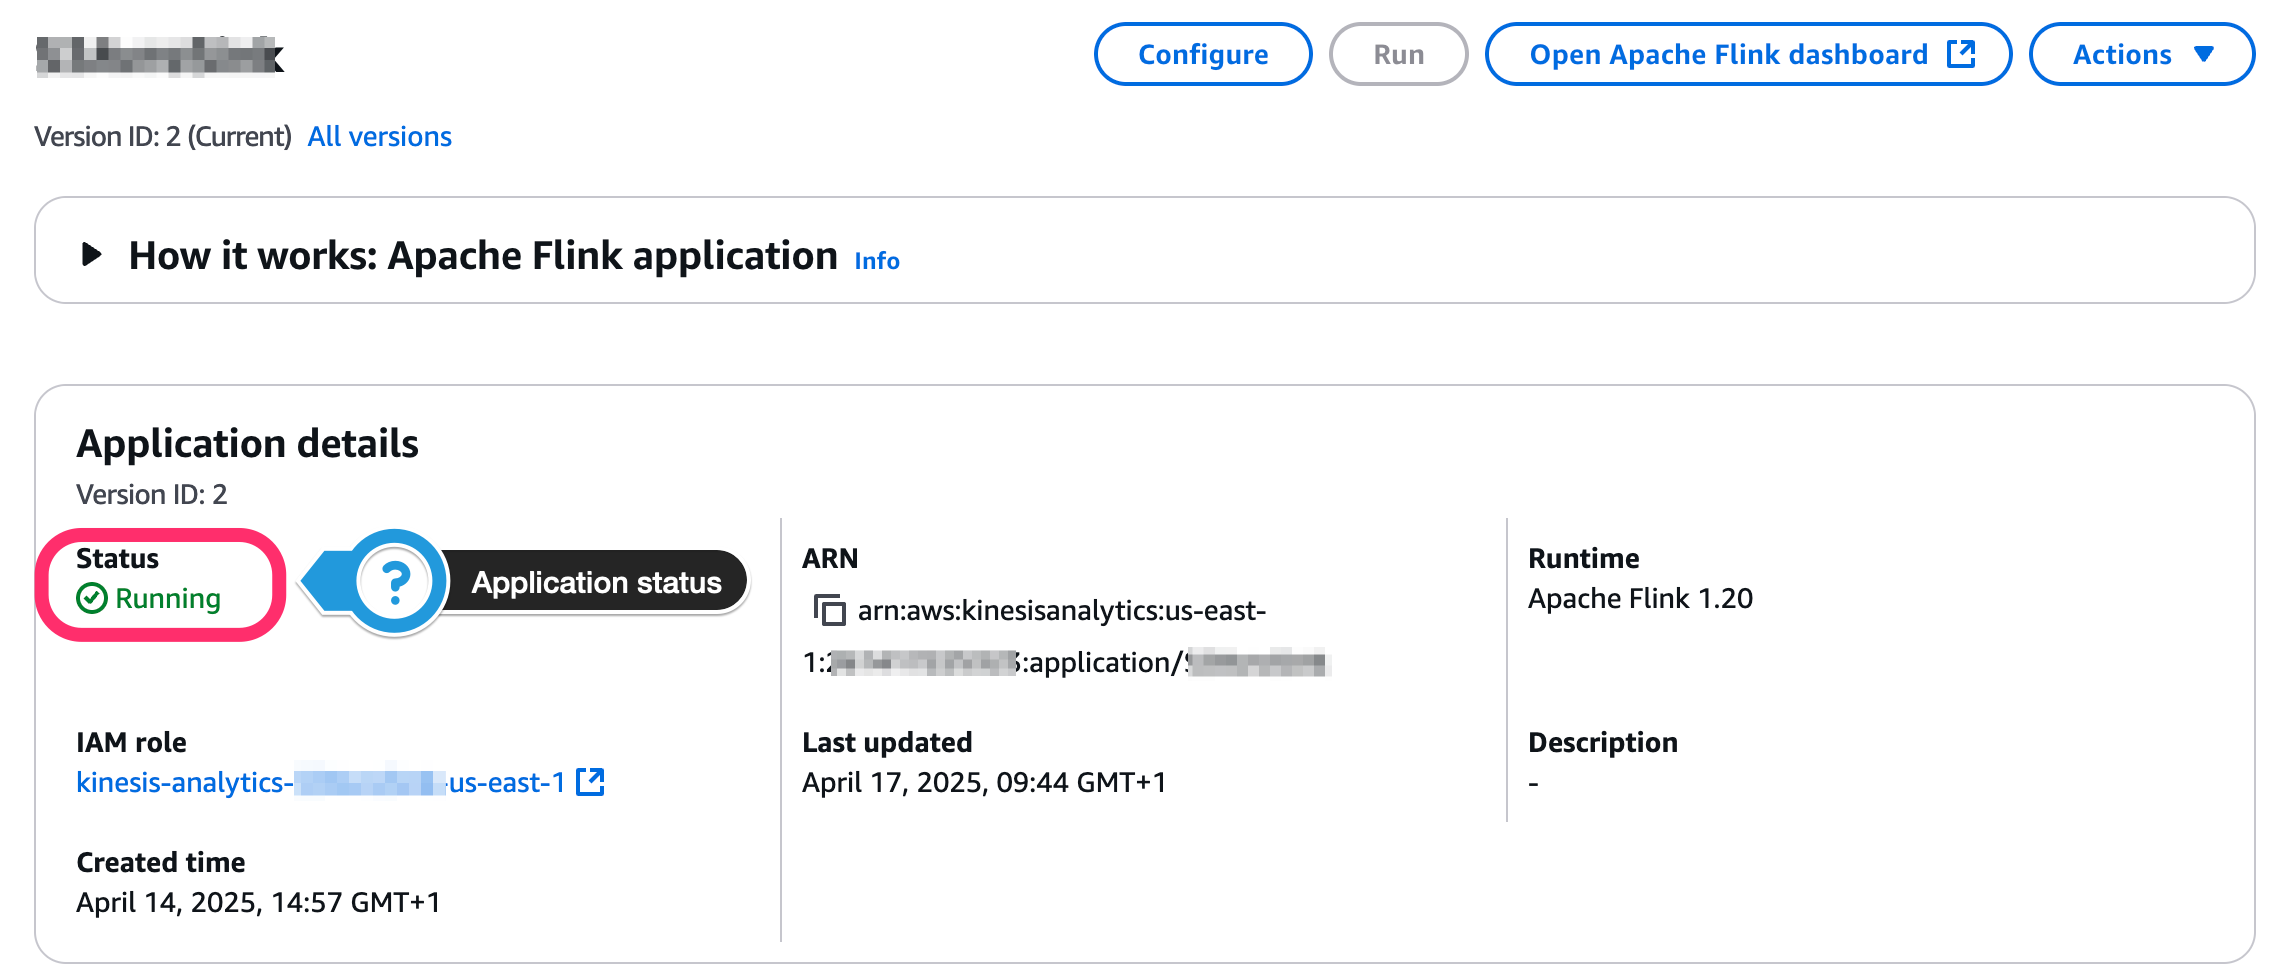
In your automation, you can poll the DescribeApplication API action to observe the application status. The following command shows how to use the AWS Command Line Interface (AWS CLI) and jq command to extract the status string of an application:
Observing job and subtask status
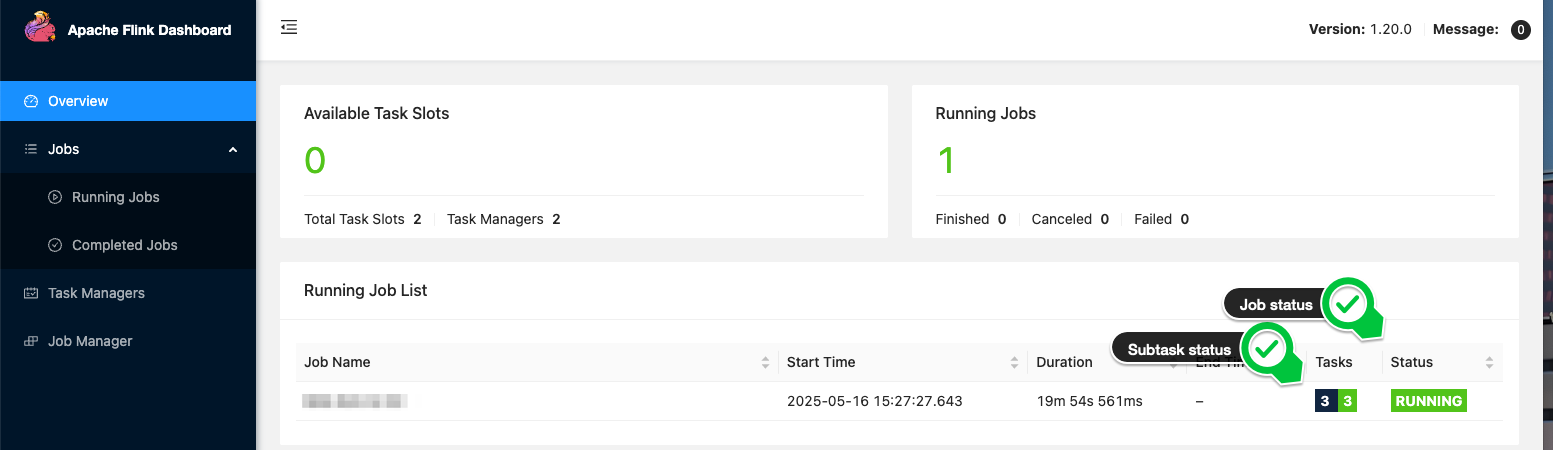
Managed Service for Apache Flink gives you access to the Flink Dashboard, which provides useful information for troubleshooting, including the status of all subtasks. The following screenshot, for example, shows a healthy job where all subtasks are RUNNING.
In the following screenshot, we can see a job where subtasks are failing and restarting.
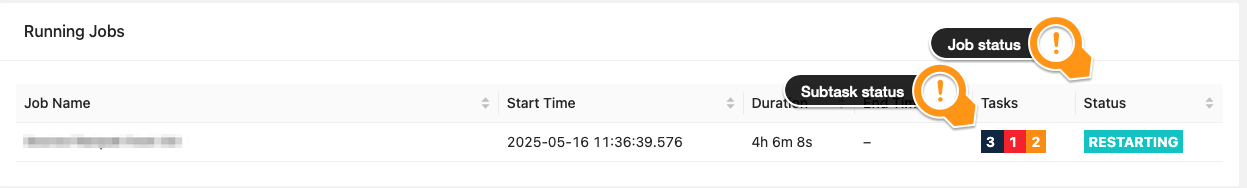
In your automation, when you start the application or deploy a change, you want to be sure the job is eventually up and running and processing data. This happens when all the subtasks are RUNNING. Note that waiting for the job status to become RUNNING after an operation is not completely safe. A subtask might still fail and cause the job to restart after it was reported as RUNNING.
After you execute a lifecycle operation, your automation can poll the substasks status waiting for one of two events:
- All subtasks report
RUNNING– This indicates the operation was successful and your Flink job is up and running. - Any subtask reports
FAILINGorCANCELED– This indicates something went wrong, and the application is likely stuck in a fail-and-restart loop. You need to intervene, for example, force-stopping the application and then rolling back the change.
If you are restarting from a snapshot and the state of your application is quite big, you might observe subtasks will report INITIALIZING status for longer. During the initialization, Flink restores the state of the operator before changing to RUNNING.
The Flink REST API exposes the state of the subtasks, and can be used in your automation. In Managed Service for Apache Flink, this requires three steps:
- Generate a pre-signed URL to access the Flink REST API using the CreateApplicationPresignedUrl API action.
- Make a GET request to the
/jobsendpoint of the Flink REST API to retrieve the job ID. - Make a GET request to the
/jobs/<job-id>endpoint to retrieve the status of the subtasks.
The following GitHub repository provides a shell script to retrieve the status of the tasks of a given Managed Service for Apache Flink application.
Monitoring subtasks failure while the job is running
The approach of polling the Flink REST API can be used in your automation, immediately after an operation, to observe whether the operation was eventually successful.
We strongly recommend not to continuously poll the Flink REST API while the job is running to detect failures. This operation is resource consuming, and might degrade performance or cause errors.
To monitor for suspicious subtask status changes during normal operations, we recommend using CloudWatch Logs instead. The following CloudWatch Logs Insights query extracts all subtask state transitions:
How Managed Service for Apache Flink minimizes processing downtime
We have seen how Flink is designed for strong consistency. To guarantee exactly-once state consistency, Flink temporarily stops the processing to deploy any changes, including scaling. This downtime is required for Flink to take a consistent copy of the application state and save it in a savepoint. After the change is deployed, the job is restarted from the savepoint, and there is no data loss. In Managed Service for Apache Flink, updates are fully managed. When snapshots are enabled, UpdateApplication automatically stops the job and uses snapshots (based on Flink’s savepoints) to retain the state.
Flink guarantees no data loss. However, your business requirements or Service Level Objectives (SLOs) might also impose a maximum delay for the data received by downstream systems, or end-to-end latency. This delay is affected by the processing downtime, or the time the job doesn’t process data to allow Flink deploying the change.With Flink, some processing downtime is unavoidable. However, Managed Service for Apache Flink is designed to minimize the processing downtime when you deploy a change.
We have seen how the service runs your application in a dedicated cluster, for complete isolation. When you issue UpdateApplication on a RUNNING application, the service prepares a new cluster with the required amount of resources. This operation might take some time. However, this doesn’t affect the processing downtime, because the service keeps the job running and processing data on the original cluster until the last possible moment, when the new cluster is ready. At this point, the service stops your job with a savepoint and restarts it on the new cluster.
During this operation, you are only charged for the number of KPU of a single cluster.
The following diagram illustrates the difference between the duration of the update operation, or the time the application status is UPDATING, and the processing downtime, observable from the job status, visible in the Flink Dashboard.
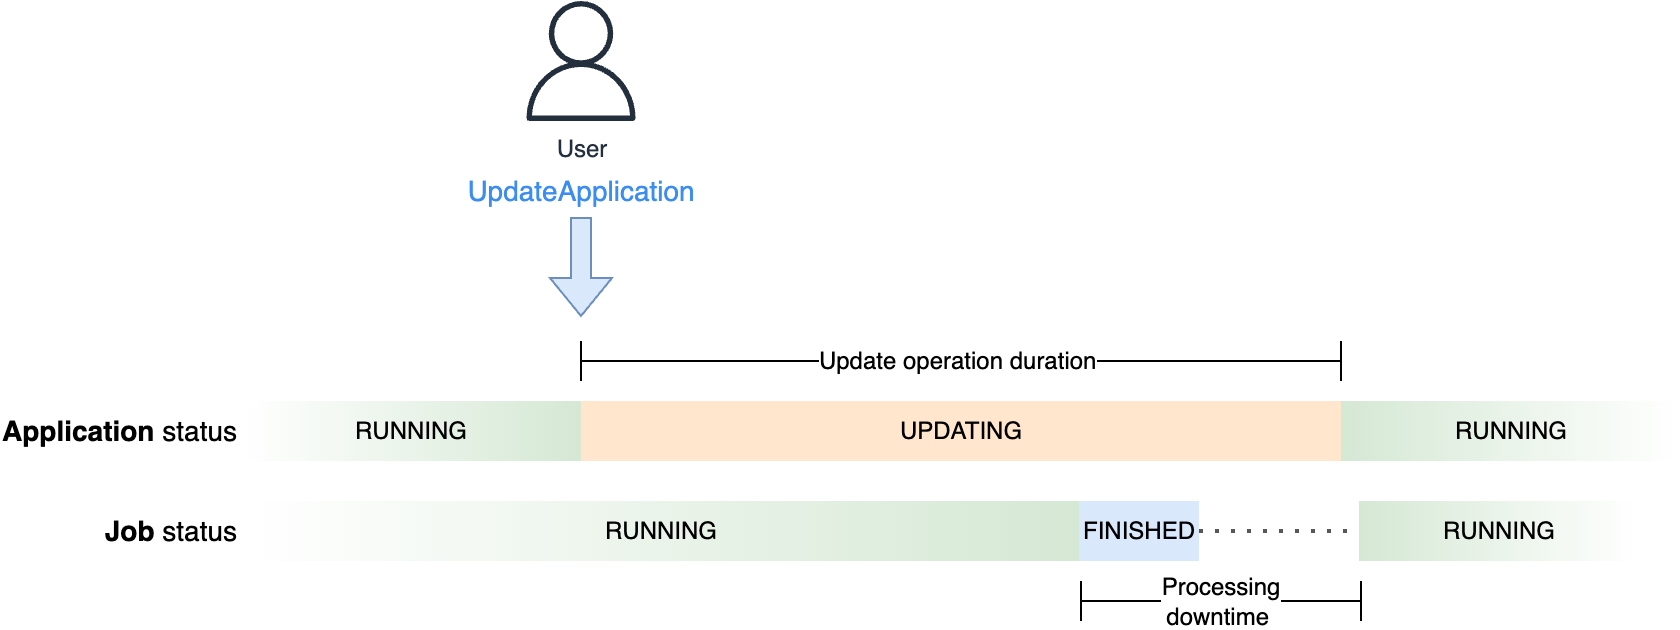
You can observe this process, keeping both the application console and Flink Dashboard open, when you update the configuration of a running application, even with no changes. The Flink Dashboard will become temporarily unavailable when the service switches to the new cluster. Additionally, you can’t use the script we provided to check the job status for this scope. Even though the cluster keeps serving the Flink Dashboard until it’s tore down, the CreateApplicationPresignedUrl action doesn’t work while the application is UPDATING.
The processing time (the time the job is not running on either clusters) depends on the time the job takes to stop with a savepoint (snapshot) and restore the state in the new cluster. This time largely depends on the size of the application state. Data skew might also affect the savepoint time due to the barrier alignment mechanism. For a deep dive into the Flink’s barrier alignment mechanism, refer to Optimize checkpointing in your Amazon Managed Service for Apache Flink applications with buffer debloating and unaligned checkpoints, keeping in mind that savepoints are always aligned.
For the scope of your automation, you normally want to wait until the job is back up and running and processing data. You normally want to set a timeout. If both the application and job don’t return to RUNNING within this timeout, something probably went wrong and you might want to raise an alarm or force a rollback. This timeout should consider the entire update operation duration.
Conclusion
In this post, we discussed possible failure scenarios when you deploy a change or scale your application. We showed how Managed Service for Apache Flink rollback functionalities can seamlessly bring you back to a safe place after a change went wrong. We also explored how you can automate monitoring operations to observe application, job, and subtask status, and how to use the fullRestarts metric to detect when the job is in a fail-and-restart loop.
For more information, see Run a Managed Service for Apache Flink application, Implement fault tolerance in Managed Service for Apache Flink, and Manage application backups using Snapshots.
About the authors
Deep dive into the Amazon Managed Service for Apache Fink application lifecycle – Part 1
Post Syndicated from Lorenzo Nicora original https://aws.amazon.com/blogs/big-data/part-1-deep-dive-into-the-amazon-managed-service-for-apache-fink-application-lifecycle/
Apache Flink is an open source framework for stream and batch processing applications. It excels in handling real-time analytics, event-driven applications, and complex data processing with low latency and high throughput. Flink is designed for stateful computation with exactly-once consistency guarantees for the application state.
Amazon Managed Service for Apache Flink is a fully managed stream processing service that you can use to run Apache Flink jobs at scale without worrying about managing clusters and provisioning resources. You can focus on implementing your application using your integrated development environment (IDE) of choice, and build and package the application using standard build and continuous integration and delivery (CI/CD) tools.
With Managed Service for Apache Flink, you can control the application lifecycle through simple AWS API actions. You can use the API to start and stop the application, and to apply any changes to the code, runtime configuration, and scale. The service takes care of managing the underlying Flink cluster, giving you a serverless experience. You can implement automation such as CI/CD pipelines with tools that can interact with the AWS API or AWS Command Line Interface (AWS CLI).
You can control the application using the AWS Management Console, AWS CLI, AWS SDK, and tools using the AWS API, such as AWS CloudFormation or Terraform. The service is not prescriptive on the automation tool you use to deploy and orchestrate the application.
Paraphrasing Jackie Stewart, the famous racing driver, you don’t need to understand how to operate a Flink cluster to use Managed Service for Apache Flink, but some Mechanical Sympathy will help you implement a robust and reliable automation.
In this two-part series, we explore what happens during an application’s lifecycle. This post covers core concepts and the application workflow during normal operations. In Part 2, we look at potential failures, how to detect them through monitoring, and ways to quickly resolve issues when they occur.
Definitions
Before examining the application lifecycle steps, we need to clarify the usage of certain terms in the context of Managed Service for Apache Flink:
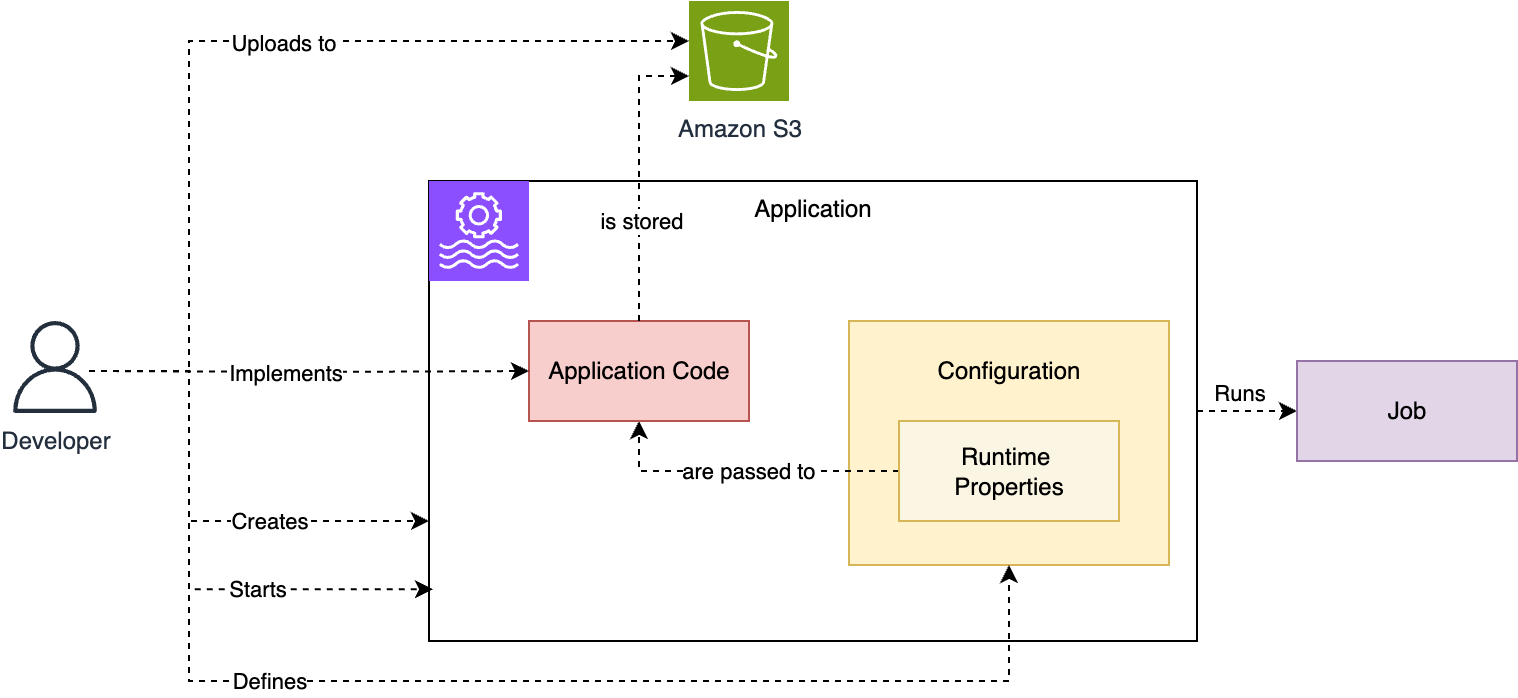
- Application – The main resource you create, control, and run in Managed Service for Apache Flink is an application.
- Application code package – For each Managed Service for Apache Flink application, you implement the application code package (application artifact) of the Flink application code you want to run. This code is compiled and packaged along with dependencies into a JAR or a ZIP file, that you upload to an Amazon Simple Storage Service (Amazon S3) bucket.
- Configuration – Each application has a configuration that contains the information to run it. The configuration points to the application code package in the S3 bucket and defines the parallelism, which will also determine the application resources, in terms of KPUs. It also defines security, networking, and runtime properties, which are passed to your application code at runtime.
- Job – When you start the application, Managed Service for Apache Flink creates a dedicated cluster for you and runs your application code as a Flink job.
The following diagram shows the relationship between these concepts.
There are two additional important concepts: checkpoints and savepoints, the mechanisms Flink uses to guarantee state consistency across failures and operations. In Managed Service for Apache Flink, both checkpoints and savepoints are fully managed.
- Checkpoints – These are controlled by the application configuration and enabled by default with a period of 1 minute. In Managed Service for Apache Flink, checkpoints are used when a job automatically restarts after a runtime failure. They are not durable and are deleted when the application is stopped or updated and when the application automatically scales.
- Savepoints – These are called snapshots in Managed Service for Apache Flink, and are used to persist the application state when the application is deliberately restarted by the user, due to an update or an automatic scaling event. Snapshots can be triggered by the user. Snapshots (if enabled) are also automatically used to save and restore the application state when the application is stopped and restarted, for example to deploy a change or automatically scale. Automatic use of snapshots is enabled in the application configuration (enabled by default when you create an application using the console).
Lifecycle of an application in Managed Service for Apache Flink
Starting with the happy path, a typical lifecycle of a Managed Service for Apache Flink application comprises the following steps:
- Create and configure a new application.
- Start the application.
- Deploy a change (update the runtime configuration, update the application code, change the parallelism to scale up or down).
- Stop the application.
Starting, stopping, and updating the application use snapshots (if enabled) to retain application state consistency during operations. We recommend enabling snapshots on every production and staging application, to support the persistence of the application state across operations.
In Managed Service for Apache Flink, the application lifecycle is controlled through the console, API actions in the kinesisanalyticsv2 API, or equivalent actions in the AWS CLI and SDK. On top of these fundamental operations, you can build your own automation using different tools, directly using low-level actions or using higher level infrastructure-as-code (IaC) tooling such as AWS CloudFormation or Terraform.
In this post, we refer to the low-level API actions used at each step. Any higher-level IaC tooling will use combination of these operations. Understanding these operations is fundamental to designing a robust automation.
The following diagram summarizes the application lifecycle, showing typical operations and application statuses.
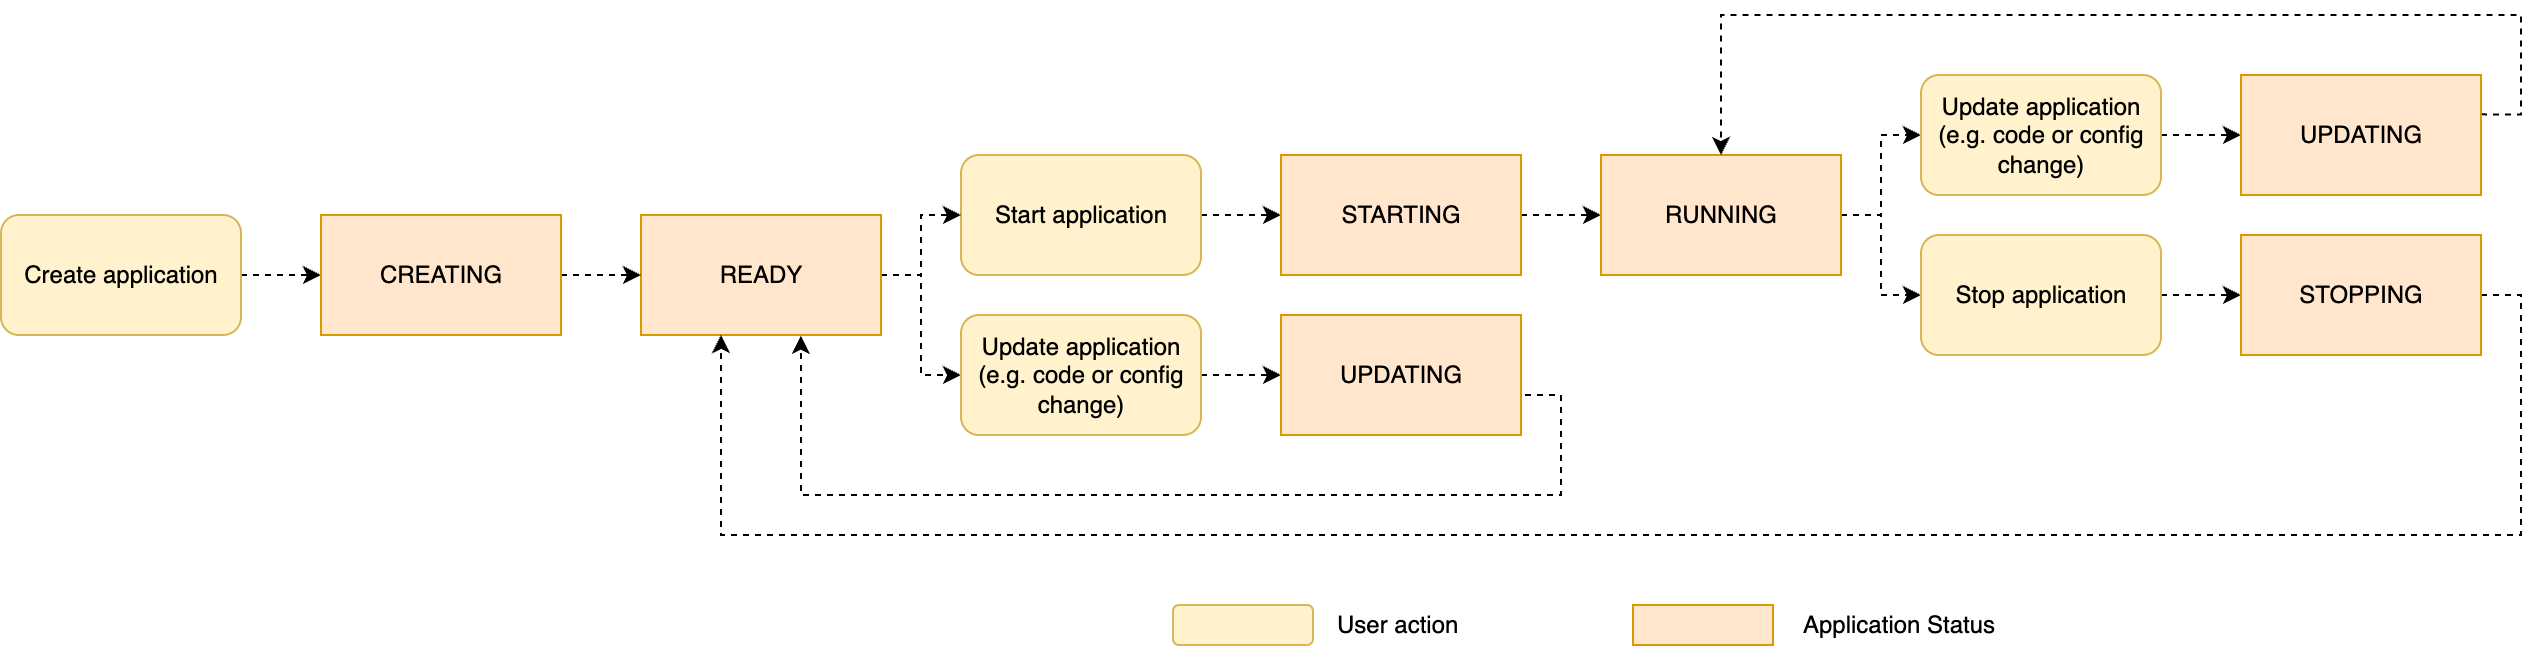
The status of your application, READY, STARTING, RUNNING, UPDATING, and so on, can be observed on the console and using the DescribeApplication API action.
In the following sections, we analyze each lifecycle operation in more detail.
Create and configure the application
The first step is creating a new Managed Service for Apache Flink application, including defining the application configuration. You can do this in a single step using the CreateApplication action, or by creating the basic application configuration and then updating the configuration before starting it using UpdateApplication. The latter approach is what you do when you create an application from the console.
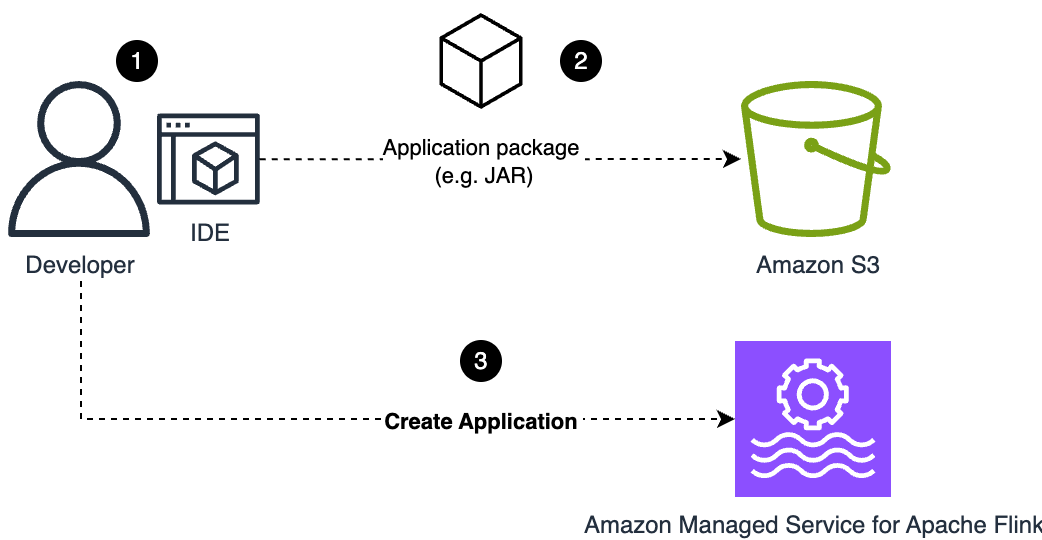
In this phase, the developer packages the application they have implemented in a JAR file (for Java) or ZIP file (for Python) and uploads it to an S3 bucket the user has previously created. The bucket name and the path to the application code package are part of the configuration you define.
When UpdateApplication or CreateApplication is invoked, Managed Service for Apache Flink takes a copy of the application code package (JAR or ZIP file) referred by the configuration. The configuration is rejected if the file pointed by the configuration doesn’t exist.
The following diagram illustrates this workflow.
Simply updating the application code package in the S3 bucket doesn’t trigger an update. You need to run UpdateApplication to make the new file visible to the service and trigger the update, even when you overwrite the code package with the same name.
Start the application
Managed Service for Apache Flink provisions resources when the application is actually running, and you only pay for the resources of running applications. You explicitly control when to start the application by issuing a StartApplication.
Managed Service for Apache Flink indexes on high availability and runs your application in a dedicated Flink cluster. When you start the application, Managed Service for Apache Flink deploys a dedicated cluster and deploys and runs the Flink job based on the configuration you defined.
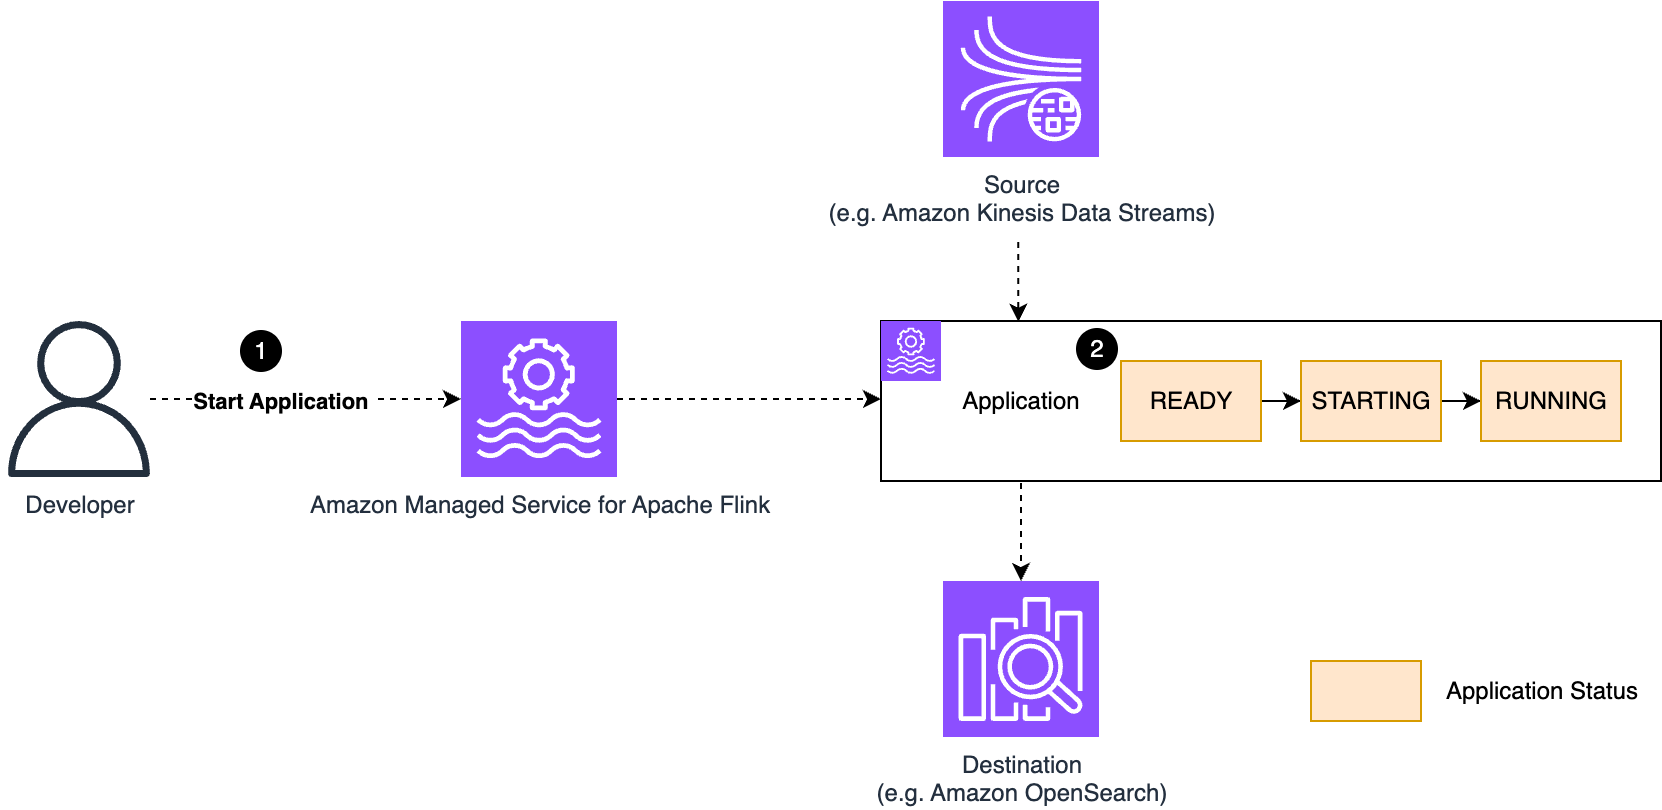
When you start the application, the status of the application moves from READY, to STARTING, and then RUNNING.
The following diagram illustrates this workflow.
Managed Service for Apache Flink supports both streaming mode, the default for Apache Flink, and batch mode:
- Streaming mode – In streaming mode, after an application is successfully started and goes into
RUNNINGstatus, it keeps running until you stop it explicitly. From this point on, the behavior on failure is automatically restarting the job from the latest checkpoint, so there is no data loss. We discuss more details about this failure scenario later in this post. - Batch mode – A Flink application running in batch mode behaves differently. After you start it, it goes into
RUNNINGstatus, and the job continues running until it completes the processing. At that point the job will gracefully stop, and the Managed Service for Apache Flink application goes back toREADYstatus.
This post focuses on streaming applications only.
Update the application
In Managed Service for Apache Flink, you handle the following changes by updating the application configuration, using the console or the UpdateApplication API action:
- Application code changes, replacing the package (JAR or ZIP file) with one containing a new version
- Runtime properties changes
- Scaling, which implies changing parallelism and resources (KPU) changes
- Operational parameter changes, such as checkpoint, logging level, and monitoring setup
- Networking configuration changes
When you modify the application configuration, Managed Service for Apache Flink creates a new configuration version, identified by a version ID number, automatically incremented at every change.
Update the code package
We mentioned how the service takes a copy of the code package (JAR or ZIP file) when you update the application configuration. The copy is associated with the new application configuration version that has been created. The service uses its own copy of the code package to start the application. You can safely replace or delete the code package after you have updated the configuration. The new package is not taken into account until you update the application configuration again.
Update a READY (not running) application
If you update an application in READY status, nothing special happens beyond creating the new configuration version that will be used the next time you start the application. However, in production, you will normally update the configuration of an application in RUNNING status to apply a change. Managed Service for Apache Flink automatically handles the operations required to update the application with no data loss.
Update a RUNNING application
To understand what happens when you update a running application, you need to remember that Flink is designed for strong consistency and exactly-once state consistency. To maintain these features when a change is applied, Flink must stop the data processing, take a copy of the application state, restart the job with the changes, and restore the state, before processing can restart.
This is a standard Flink behavior, and applies to any changes, whether it’s code changes, runtime configuration changes, or new parallelism to scale up and down. Managed Service for Apache Flink automatically orchestrates this process for you. If snapshots are enabled, the service will take a snapshot before stopping the processing and restart from the snapshot when the change is deployed. This way, the change can be deployed with zero data loss.
If snapshots are disabled, the service restarts the job with the change, but the state will be empty, like the first time you started the application. This might cause data loss. You normally don’t want this to happen, particularly in production applications.
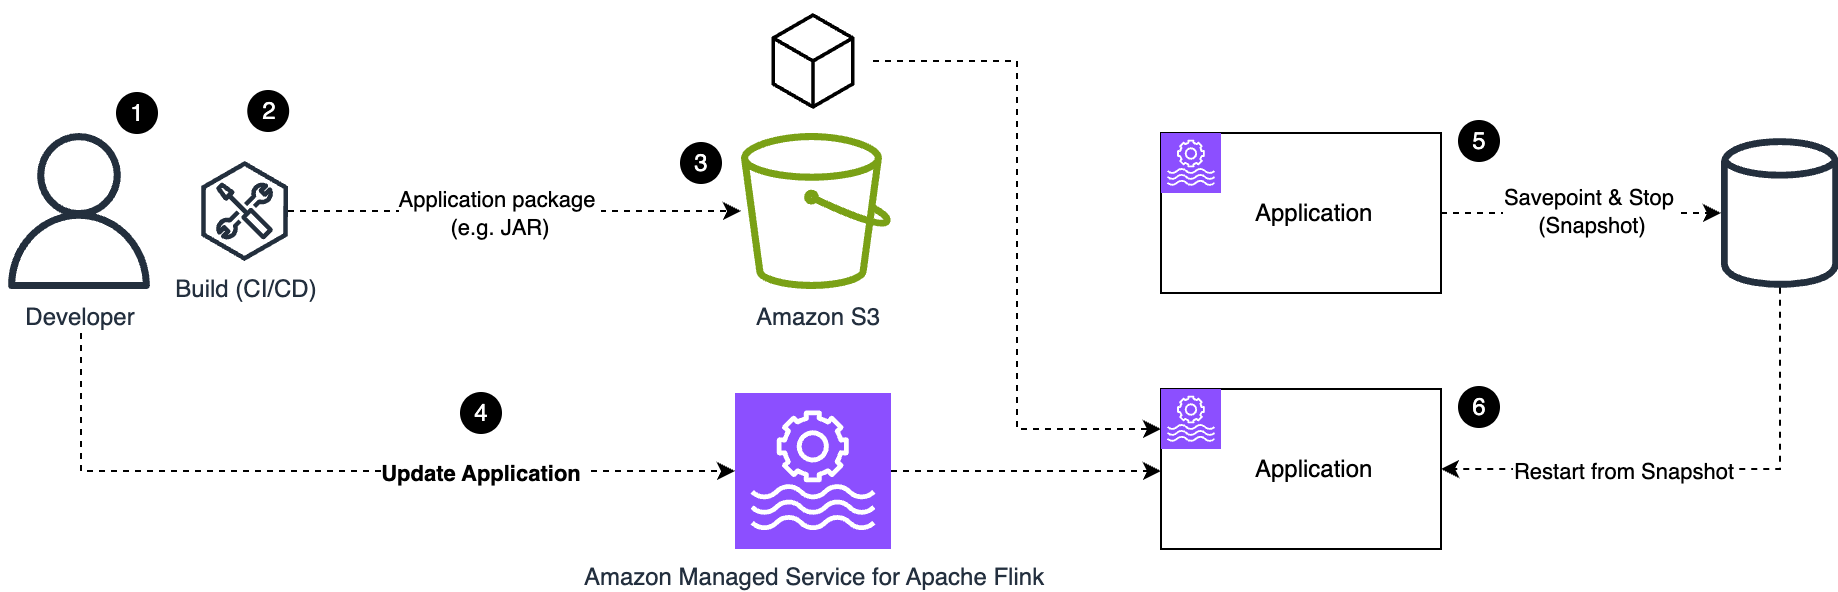
Let’s explore a practical example, illustrated by the following diagram. For instance, when you want to deploy a code change, the following steps typically happen (in this example, we assume that snapshots are enabled, which they should be in a production application):
- Make changes to the application code.
- The build process creates the application package (JAR or ZIP file), either manually or using CI/CD automation.
- Upload the new application package to an S3 bucket.
- Update the application configuration pointing to the new application package.
- As soon as you successfully update the configuration, Managed Service for Apache Flink starts the operation for updating the application. The application status changes to
UPDATING. The Flink job is stopped, taking a snapshot of the application state. - After the changes have been applied, the application is restarted using the new configuration, which in this case includes the new application code, and the job restores the state from the snapshot. When the process is complete, the application status goes back to
RUNNING.
The process is similar for changes to the application configuration. For example, you can change the parallelism to scale the application updating the application configuration, causing the application to be redeployed with the new parallelism and the amount resources (CPU, memory, local storage) based on the new number of KPU.
Update the application’s IAM role
The application configuration contains a reference to an AWS Identity and Access Management (IAM) role. In the unlikely case you want to use a different role, you can update the application configuration using UpdateApplication. The process will be the same described earlier.
However, you usually want to modify the IAM role, to add or remove permissions. This operation doesn’t use the Managed Service for Apache Flink application lifecycle and can be done at any time. No application stop and restart is required. IAM changes take effect immediately, potentially inducing a failure if, for example, you inadvertently remove a required permission. In this case, the behavior of the Flink job’s response might vary, depending on the affected component.
Stop the application
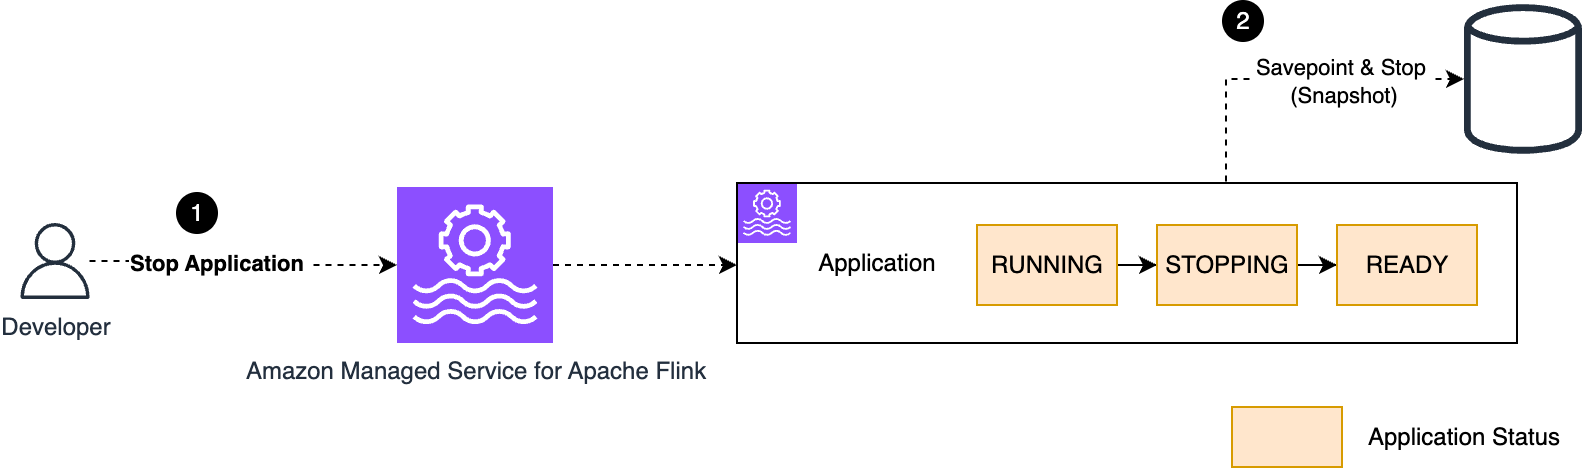
You can stop a running Managed Service for Apache Flink application using the StopApplication action or the console. The service gracefully stops the application. The state turns from RUNNING, into STOPPING, and finally into READY.
When snapshots are enabled, the service will take a snapshot of the application state when it is stopped, as shown in the following diagram.
After you stop the application, any resource previously provisioned to run your application is reclaimed. You incur no cost while the application is not running (READY).
Start the application from a snapshot
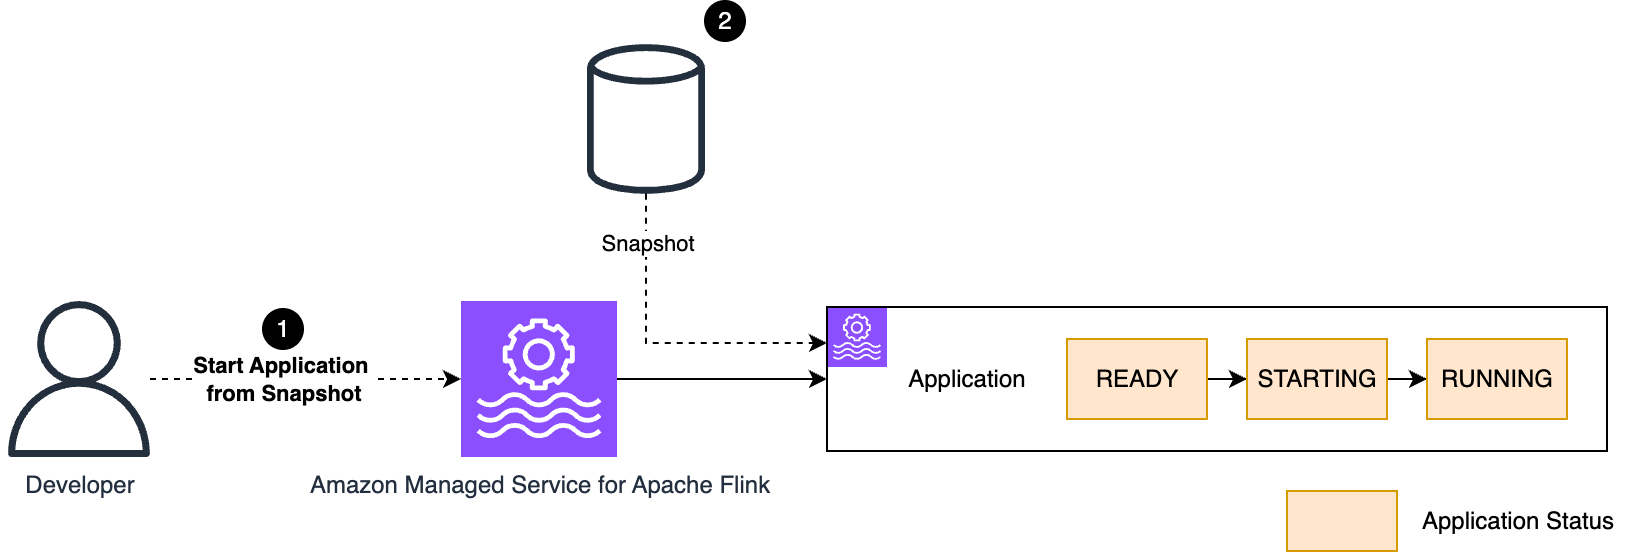
Sometimes, you might want to stop a production application and restart it later, restarting the processing from the point it was stopped. Managed Service for Apache Flink supports starting the application from a snapshot. The snapshot saves not only the application state, but also the point in the source—the offsets in a Kafka topic, for example—where the application stopped consuming.
When snapshots are enabled, Managed Service for Apache Flink automatically takes a snapshot when you stop the application. This snapshot can be used when you restart the application.
The StartApplication API command has three restore options:
RESTORE_FROM_LATEST_SNAPSHOT: Restore from the latest snapshot.RESTORE_FROM_CUSTOM_SNAPSHOT: Restore from a custom snapshot (you need to specify which one).SKIP_RESTORE_FROM_SNAPSHOT: Skip restoring from the snapshot. The application will start with no state, as the very first time you ran it.
When you start the application for the very first time, no snapshot is available yet. Regardless of the restore option you choose, the application will start with no snapshot.
The process of starting the application from a snapshot is visualized in the following diagram.
In production, you normally want to restore from the latest snapshot (RESTORE_FROM_LATEST_SNAPSHOT). This will automatically use the snapshot the service created when you last stopped the application.
Snapshots are based on Flink’s savepoint mechanism and maintain the exactly-once consistency of the internal state. Also, the risk of reprocessing duplicate records from the source is minimized because the snapshot is taken synchronously while the Flink job is stopped.
Start the application from an older snapshot
In Managed Service for Apache Flink, you can schedule taking periodic snapshots of a running production application, for example using the Snapshot Manager. Taking a snapshot from a running application doesn’t stop the processing and only introduces a minimal overhead (comparable to checkpointing). With the second option, RESTORE_FROM_CUSTOM_SNAPSHOT, you can restart the application back in time, using a snapshot older than the one taken on the last StopApplication.
Because the source positions—for example, the offsets in a Kafka topic—are also restored with the snapshot, the application will revert to the point the application was processing when the snapshot was taken. This will also restore the state at that exact point, providing consistency.
When you start an application from an older snapshot, there are two important considerations:
- Only restore snapshots taken within the source system retention period – If you restore a snapshot older than the source retention, data loss might occur, and the application behavior is unpredictable.
- Restarting from an older snapshot will likely generate duplicate output – This is often not a problem when the end-to-end system is designed to be idempotent. However, this might cause problems if you are using a Flink transactional connector, such as File System sink or Kafka sink with exactly-once guarantees enabled. Because these sinks are designed to guarantee no duplicates (preventing them at any cost), they might prevent your application from restarting from an older snapshot. There are workarounds to this operational problem, but they depend on the specific use case and are beyond the scope of this post.
Understanding what happens when you start your application
We have learned the fundamental operations in the lifecycle of an application. In Managed Service for Apache Flink, these operations are controlled by a few API actions, such as StartApplication, UpdateApplication, and StopApplication. The service controls every operation for you. You don’t have to provision or manage Flink clusters. However, a better understanding of what happens during the lifecycle will give you sufficient Mechanical Sympathy to recognize potential failure modes and implement a more robust automation.
Let’s see in detail what happens when you issue a StartApplication command on an application in READY (not running). When you issue an UpdateApplication command on a RUNNING application, the application is first stopped with a snapshot, and then restarted with the new configuration, with a process identical to what we are going to see.
Composition of a Flink cluster
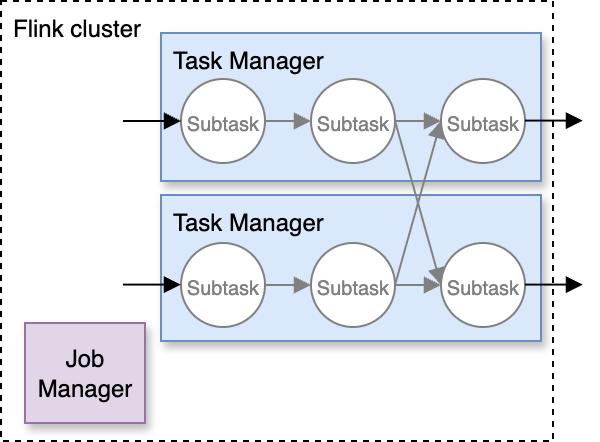
To understand what happens when you start the application, we need to introduce a couple of additional concepts. A Flink cluster is comprised of two types of nodes:
- A single Job Manager, which acts as a coordinator
- One or more Task Managers, which do the actual data processing
In Managed Service for Apache Flink, you can see the cluster nodes in the Flink Dashboard, which you can access from the console.
Flink decomposes the data processing defined by your application code into one or more subtasks, which are distributed across the Task Manager nodes, as illustrated in the following diagram.
Remember, in Managed Service for Apache Flink, you don’t need to worry about provisioning and configuring the cluster. The service provides a dedicated cluster for your application. The total amount of vCPU, memory, and local storage of Task Managers matches the number of KPU you configured.
Starting your Managed Service for Apache Flink application
Now that we’ve discussed how a Flink cluster is composed, let’s explore what happens when you issue a StartApplication command, or when the application restarts after a change has been deployed with an UpdateApplication command.
The following diagram illustrates the process. Everything is carried out automatically for you.
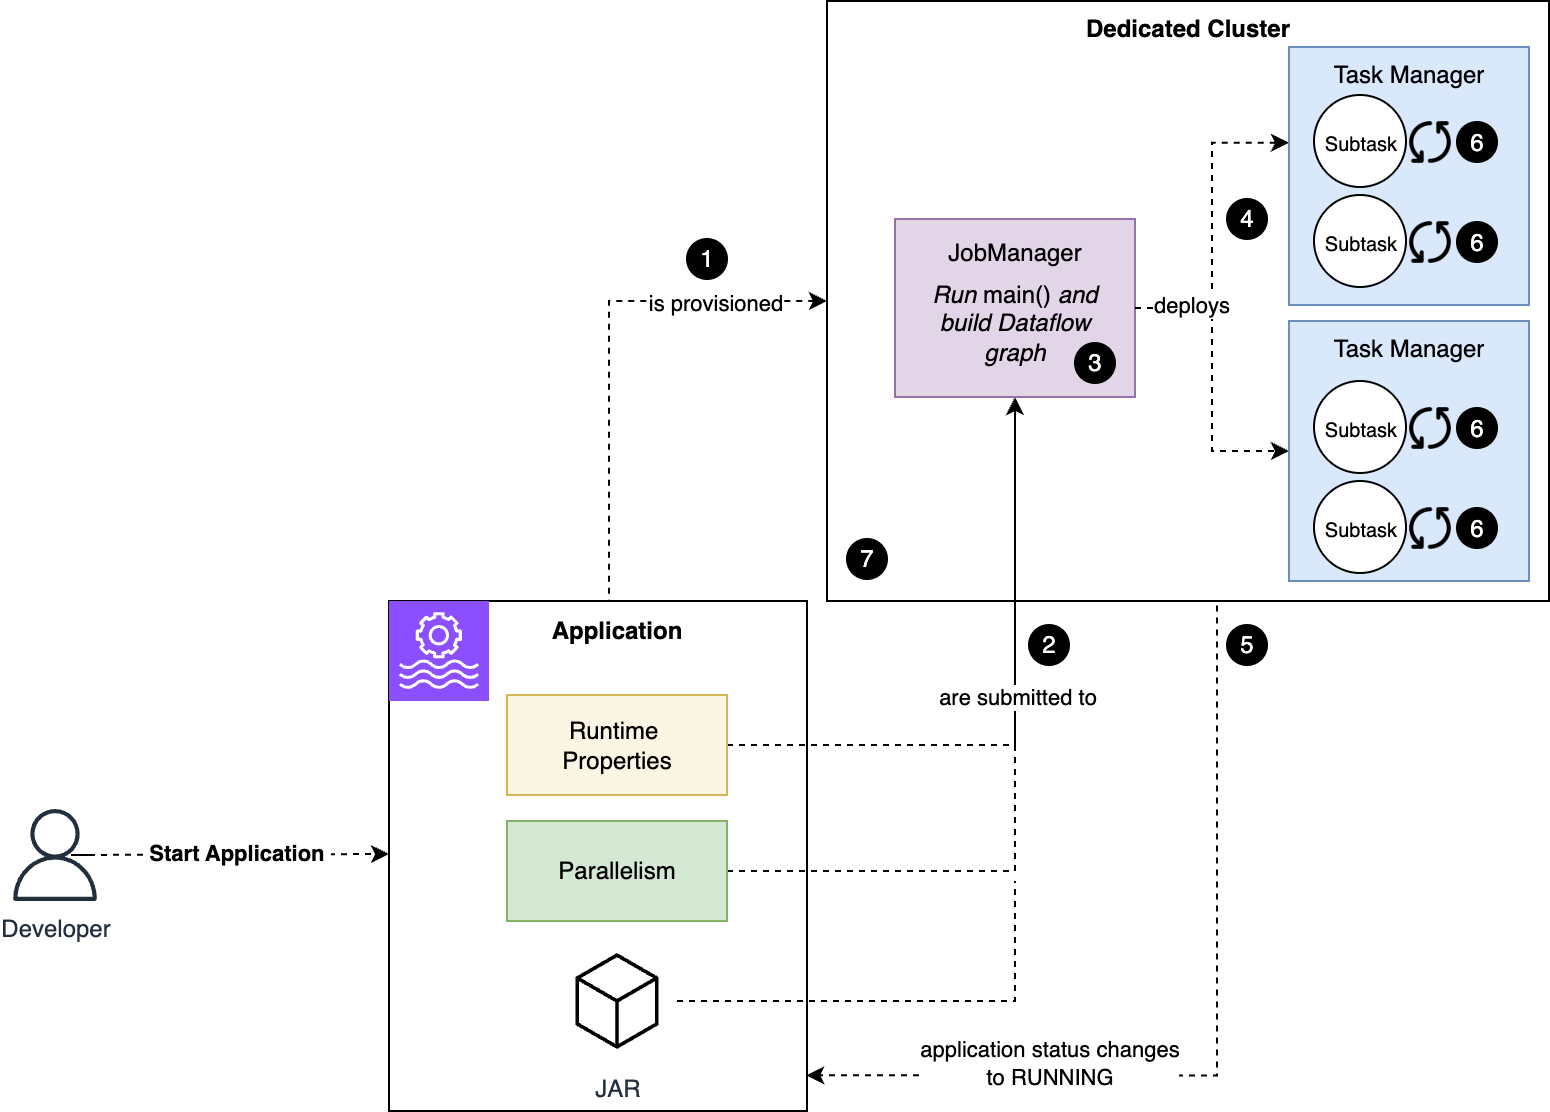
The workflow consists of the following steps:
- A dedicated cluster, with the amount of resources you requested, based on the number of KPU, is provisioned for your application.
- The application code, runtime properties, and other configurations such as the application parallelism are passed to the Job Manager node, the coordinator of the cluster.
- The Java or Python code in the
main()method of your application is executed. This generates the logical graph of operators of your application (called dataflow). Based on the dataflow you defined and the application parallelism, Flink generates the subtasks, the actual nodes Flink will execute to process your data. - Flink then distributes the job’s subtasks across Task Managers, the actual worker nodes of the cluster.
- When the previous step succeeds, the Flink job status and the Managed Service for Apache Flink application status change to
RUNNING. However, the job is still not completely running and processing data. All substasks must be initialized. - Each subtask independently restores its state, if starting from a snapshot, and initializes runtime resources. For example, Flink’s Kafka source connector restores the partition assignments and offsets from the savepoint (snapshot), establishes a connection to the Kafka cluster, and subscribes to the Kafka topic. From this step onward, a Flink job will stop and restart from its last checkpoint when encountering any unhandled error. If the problem causing the error is not transient, the job keeps stopping and restarting from the same checkpoint in a loop.
- When all subtasks are successfully initialized and change to
RUNNINGstatus, the Flink job starts processing data and is now properly running.
Conclusion
In this post, we discussed how the lifecycle of a Managed Service for Apache Flink application is controlled by simple AWS API commands, or the equivalent using the AWS SDK or AWS CLI. If you are using high-level automation tools such as AWS CloudFormation or Terraform, the low-level actions are also abstracted away for you. The service handles the complexity of operating the Flink cluster and orchestrating the Flink job lifecycle.
However, with a better understanding of how Flink works and what the service does for you, you can implement more robust automation and troubleshoot failures.
In the Part 2, we continue examining failure scenarios that can happen during normal operations or when you deploy a change or scale the application, and how to monitor operations to detect and recover when something goes wrong.
About the authors
The One Book Everyone Should Read
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/8RSrYLRzRC8
Home Assistant 2025.9 released
Post Syndicated from corbet original https://lwn.net/Articles/1036635/
Version
2025.9 of the Home Assistant home automation system has been released.
Changes include a new experimental dashboard that is eventually meant to
become the default, a number of tile-card improvements, a reworked
automation editor, several new integrations, and more.
Niri 25.08 released
Post Syndicated from jzb original https://lwn.net/Articles/1036625/
Version
25.08 of the niri scrollable-tiling Wayland compositor has been
released. Notable changes include xwayland-satellite
integration, modal exit confirmation, and the introduction of basic
support for screen readers:
A series
of posts by fireborn earlier this year on the screen reader
situation in Linux got me curious: how does one support
screen readers in a Wayland compositor? The documentation is
unfortunately scarce and difficult to find. Thankfully, @DataTriny from the AccessKit project came across my issue,
pointed me at the right protocols, and answered a lot of my questions.So, as of this release, niri has basic support for screen readers!
We implement the org.freedesktop.a11y.KeyboardMonitor D-Bus
interface for Orca to listen and
grab keyboard keys, and we expose the main niri UI elements via
AccessKit. […]The current screen reader support and further considerations are
documented on the new Accessibility wiki page.
LWN covered niri in
July.
Linux From Scratch 12.4 released
Post Syndicated from jzb original https://lwn.net/Articles/1036624/
Version
12.4 of Linux From Scratch (LFS) and Beyond Linux From Scratch
(BLFS) have been released. LFS
provides step-by-step instructions on building a customized Linux
system entirely from source, and BLFS helps to extend an LFS
installation into a more usable system. Notable changes in this
release include updates to GNU Binutils 2.45, GCC 15.2, GNU C Library
(glibc) 2.42, and Linux 6.15.1. See the Changelog
for all updates since 12.3.
[$] Tracking trust with Rust in the kernel
Post Syndicated from daroc original https://lwn.net/Articles/1034603/
The Linux kernel has to handle many different sources of data that should not
be trusted: user space, network connections, and removable storage, to name a
few. The kernel has to remain secure even if one of these sends garbled (or
malicious) data. Benno Lossin has been working on an API for kernel Rust code
that makes it harder to accidentally make decisions based on data from user space. That work
is now on its
fourth revision, and Lossin has asked kernel developers to experiment with
it and see where problems remain, making this a good time to look at the proposed API.
Announcing the Rust Innovation Lab
Post Syndicated from daroc original https://lwn.net/Articles/1035169/
During the opening of RustConf 2025 in Seattle, Washington,
the Rust Foundation announced
a new initiative to provide financial and administrative support to open-source Rust projects. The first project to benefit from the new Rust Innovation Lab is
Rustls, an implementation of TLS in Rust. The foundation welcomes inquiries from other projects. Dr. Rebecca Rumbul, Executive Director of the Rust Foundation said:
Rustls is hopefully the first of many really good […] projects that will find a home in the foundation.
Jonathan Rauch on mechanisms of disinformation
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/FLTeIXjKpCY
Jonathan Rauch and the Fight for Truth | The David Frum Show
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=x4I8K7sLmUk
Home Assistant 2025.9 – The Update That Even Added… a Clock?! 🕒😂
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=7-_KedyJLvI
AI Week 2025: Recap
Post Syndicated from Kenny Johnson original https://blog.cloudflare.com/ai-week-2025-wrapup/
How do we embrace the power of AI without losing control?
That was one of our big themes for AI Week 2025, which has now come to a close. We announced products, partnerships, and features to help companies successfully navigate this new era.
Everything we built was based on feedback from customers like you that want to get the most out of AI without sacrificing control and safety. Over the next year, we will double down on our efforts to deliver world-class features that augment and secure AI. Please keep an eye on our Blog, AI Avenue, Product Change Log and CloudflareTV for more announcements.
This week we focused on four core areas to help companies secure and deliver AI experiences safely and securely:
-
Securing AI environments and workflows
-
Protecting original content from misuse by AI
-
Helping developers build world-class, secure, AI experiences
-
Making Cloudflare better for you with AI
Thank you for following along with our first ever AI week at Cloudflare. This recap blog will summarize each announcement across these four core areas. For more information, check out our “This Week in NET” recap episode also featured at the end of this blog.

These posts and features focused on helping companies control and understand their employee’s usage of AI tools.
|
Blog |
Recap |
|
Beyond the ban: A better way to secure generative AI applications |
Generative AI tools present a trade-off of productivity and data risk. Cloudflare One’s new AI prompt protection feature provides the visibility and control needed to govern these tools, allowing organizations to confidently embrace AI. |
|
Unmasking the Unseen: Your Guide to Taming Shadow AI with Cloudflare One |
Don’t let “Shadow AI” silently leak your data to unsanctioned AI. This new threat requires a new defense. Learn how to gain visibility and control without sacrificing innovation. |
|
Introducing Cloudflare Application Confidence Score For AI Applications |
Cloudflare will provide confidence scores within our application library for Gen AI applications, allowing customers to assess their risk for employees using shadow IT. |
|
ChatGPT, Claude, & Gemini security scanning with Cloudflare CASB |
Cloudflare CASB now scans ChatGPT, Claude, and Gemini for misconfigurations, sensitive data exposure, and compliance issues, helping organizations adopt AI with confidence. |
|
Securing the AI Revolution: Introducing Cloudflare MCP Server Portals |
Cloudflare MCP Server Portals are now available in Open Beta. MCP Server Portals are a new capability that enable you to centralize, secure, and observe every MCP connection in your organization. |
|
This guide provides best practices for Security and IT leaders to securely adopt generative AI using Cloudflare’s SASE architecture as part of a strategy for AI Security Posture Management (AI-SPM). |

Cloudflare is committed to helping content creators control access to their original work. These announcements focused on analysis of what we’re currently seeing on the Internet with respect to AI bots and crawlers and significant improvements to our existing control features.
|
Blog |
Recap |
|
A deeper look at AI crawlers: breaking down traffic by purpose and industry |
We are extending AI-related insights on Cloudflare Radar with new industry-focused data and a breakdown of bot traffic by purpose, such as training or user action. |
|
The age of agents: cryptographically recognizing agent traffic |
Cloudflare now lets websites and bot creators use Web Bot Auth to segment agents from verified bots, making it easier for customers to allow or disallow the many types of user and partner directed. |
|
Make Your Website Conversational for People and Agents with NLWeb and AutoRAG |
With NLWeb, an open project by Microsoft, and Cloudflare AutoRAG, conversational search is now a one-click setup for your website. |
|
The next step for content creators in working with AI bots: Introducing AI Crawl Control |
Cloudflare launches AI Crawl Control (formerly AI Audit) and introduces easily customizable 402 HTTP responses. |
|
The crawl-to-click gap: Cloudflare data on AI bots, training, and referrals |
By mid-2025, training drives nearly 80% of AI crawling, while referrals to publishers (especially from Google) are falling and crawl-to-refer ratios show AI consumes far more than it sends back. |

At Cloudflare we are committing to building the best platform to build AI experiences, all with security by default.
|
Blog |
Recap |
|
AI Gateway now gives you access to your favorite AI models, dynamic routing and more — through just one endpoint. |
|
|
How we built the most efficient inference engine for Cloudflare’s network |
Infire is an LLM inference engine that employs a range of techniques to maximize resource utilization, allowing us to serve AI models more efficiently with better performance for Cloudflare workloads. |
|
We’re expanding Workers AI with new partner models from Leonardo.Ai and Deepgram. Start using state-of-the-art image generation models from Leonardo and real-time TTS and STT models from Deepgram. |
|
|
How Cloudflare runs more AI models on fewer GPUs: A technical deep-dive |
Cloudflare built an internal platform called Omni. This platform uses lightweight isolation and memory over-commitment to run multiple AI models on a single GPU. |
|
Cloudflare Launching AI Miniseries for Developers (and Everyone Else They Know) |
In AI Avenue, we address people’s fears, show them the art of the possible, and highlight the positive human stories where AI is augmenting — not replacing — what people can do. And yes, we even let people touch AI themselves. |
|
Block unsafe prompts targeting your LLM endpoints with Firewall for AI |
Cloudflare’s AI security suite now includes unsafe content moderation, integrated into the Application Security Suite via Firewall for AI. |
|
Today, we’re excited to announce new capabilities that make it easier than ever to build real-time, voice-enabled AI applications on Cloudflare’s global network. |

Cloudflare logs and analytics can often be a needle in the haystack challenge, AI helps surface and alert to issues that need attention or review. Instead of a human having to spend hours sifting and searching for an issue, they can focus on action and remediation while AI does the sifting.
|
Blog |
Except |
|
Evaluating image segmentation models for background removal for Images |
An inside look at how the Images team compared dichotomous image segmentation models to identify and isolate subjects in an image from the background. |
|
Cloudy now supercharges analytics investigations and Cloudforce One threat intelligence! Get instant insights from threat events and APIs on APTs, DDoS, cybercrime & more – powered by Workers AI! |
|
|
Cloudy Summarizations of Email Detections: Beta Announcement |
We’re now leveraging our internal LLM, Cloudy, to generate automated summaries within our Email Security product, helping SOC teams better understand what’s happening within flagged messages. |
|
Troubleshooting network connectivity and performance with Cloudflare AI |
Troubleshoot network connectivity issues by using Cloudflare AI-Power to quickly self diagnose and resolve WARP client and network issues. |
We thank you for following along this week — and please stay tuned for exciting announcements coming during Cloudflare’s 15th birthday week in September!
Check out the full video recap, featuring insights from Kenny Johnson and host João Tomé, in our special This Week in NET episode (ThisWeekinNET.com) covering everything announced during AI Week 2025.
New ELF specification for public review
Post Syndicated from jzb original https://lwn.net/Articles/1036569/
Cary Coutant has announced
a draft for version 4.3 of the
Executable and Linking Format (ELF) object file format. The
specification was formerly part of the Unix System
V Release 4 (SVR4) gABI document:
The last published gABI documents were the Fourth Edition and a draft
of Edition 4.1, both published in March 1997. The ELF portions of the
document were updated several times between 1998 and 2015, published
online […]I’ve published the last draft from 2015 as Version 4.2, and collected
the several changes since then, along with new e_machine values, as
Version 4.3.
The source for the draft is on GitHub in reStructuredText
format, and Coutant has collected the mailing list discussions for
changes in 4.3 as GitHub
issues. Thanks to Jose E. Marchesi for the tip.
Comic for 2025.09.03 – Flashlight
Post Syndicated from Explosm.net original https://explosm.net/comics/flashlight
New Cyanide and Happiness Comic
Security updates for Wednesday
Post Syndicated from jzb original https://lwn.net/Articles/1036567/
Security updates have been issued by AlmaLinux (httpd, kernel, and kernel-rt), Debian (python-eventlet and python-h2), Mageia (aide, gnutls, tomcat, and vim), Oracle (httpd, mod_http2, postgresql:15, python3.11, python3.12, python3.9, and udisks2), Red Hat (kernel, postgresql, postgresql:12, and postgresql:15), SUSE (dcmtk, jupyter-bqplot-jupyterlab, kured, libudisks2-0, munge, python-eventlet, python-future, python311-eventlet, rekor, traefik2, and ucode-intel), and Ubuntu (linux-aws, linux-azure-5.15, linux-gcp-6.8, linux-gke, linux-gkeop, linux-hwe-6.8, linux-nvidia,
linux-nvidia-6.8, linux-nvidia-lowlatency, linux-raspi, linux-gke, linux-ibm-5.15, linux-kvm, and protobuf).
Mystery of the Lost Diamond of Eagle, Wisconsin.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=mRQtixMDq4k