Welcome to the Q2 2026 Network Stats report. While we’ve been tracking trends since December 2023, this is the third quarter since we operationalized the dataset and re-launched the series, allowing ourselves to make direct, quarter-over-quarter comparisons. Why? Because AI workloads were changing traffic patterns across Backblaze’s network, and reshaping the internet.
With three quarters of historical data now available, we’re moving beyond measuring traffic volumes. We’ve been able to spot trends and start drawing conclusions—how predictable or unpredictable those workloads really are, and what that means for infrastructure that supports the next generation of AI applications.
Check out past Network Stats reports
If you’re interested in some of the trends we’ve spotted in previous reports, you can review the past reports here: Q1 2026 Q4 2025 Q3 2025
Previous analysis has been based on the amount of network traffic in bits flowing across in or out of our network, the number of bits and participants per TCP session (our coined “magnitude” metric), and regional geographic trends. In this report, you’ll find charts and heatmaps for the metrics that we’ve been reporting on over the past year, but we’re also going to use statistical analysis to answer a practical question: What kinds of traffic patterns do AI workloads create, and how should infrastructure evolve to support them?
Traffic from neocloud and hyperscaler networks are proving to be very dynamic in nature, and that’s what we’re going to explore in this quarterly report: variance.
Join the webinar
Want to hear more? Join Brent Nowak, Manager, Network Engineering, and Stephanie Doyle, Sr. Manager, Market Intelligence and Keeper of Stats, live on Tuesday, July 28, 2026 at 11:30 a.m. PT / 2:30 p.m. ET to walk through the data and spot the latest trends.
Can’t make it live? Register anyway and we’ll send you the recording.
Why look at variance?
Variance is a deep topic to explore, which involves modeling our traffic patterns against a known baseline. To analyze variance, we built a new time-series dataset using 10-minute traffic samples and modeled traffic behavior against statistical baselines. This lets us distinguish stable, predictable traffic from highly volatile workloads that demand different infrastructure planning.
I refreshed my statistics knowledge, created a new database to hold a timeseries dataset, and spent a few nights experimenting with the SciPy Python library in order to not only produce pretty graphs, but to generate a signal for us to interpret.
The types of questions that we’re interested in answering from the variance signals that affect our business include:
How quickly are AI workloads changing capacity requirements?
Which traffic patterns require different network architecture? And does our current architecture support what we’re growth modeling into the future?
Which signals represent lasting trends versus temporary spikes?
These are big questions! And exciting ones as Backblaze looks to support today and tomorrow’s workflows.
With that, let’s refresh our existing charts with this quarter’s data before diving into the new analysis on variance.
Summer heat-up
The stacked area graph below shows total traffic by network type over time updated with the most current data.
Total traffic by network type.
CDN traffic: New baseline of activity with a 66% increase from last year.
Hosting traffic: The hosting category (the light orange layer right above CDN) has remained incredibly rigid. Unlike neocloud or hyperscalers, which expand and contract elastically, hosting traffic has maintained a nearly identical bandwidth footprint for over a year.
Hyperscaler traffic: Hyperscaler traffic also followed the neocloud pattern, with the lowest amount of activity in January and remaining steady into June. Internal data sources show new workloads across all of the major hyperscalers in the past quarter.
Neocloud traffic: After a low point of activity in January, activity increased rapidly into March and has remained high until June. Internal telemetry shows that not only the amount of neocloud traffic increased in Q1 into Q2, but the number of neoclouds that we are interacting with has increased.
ISP-regional traffic: This was the dominant driver of the massive traffic spike in October 2025. While it dropped significantly into January 2026, it has aggressively rebounded through Q2 2026 and is currently the largest single driver of volume alongside neocloud.
Migration traffic: This traffic includes one way migrations into our environment, primarily serviced by partners such as Flexify.IO. We have migrations running all the time, but we can visually see large amounts around November 2025 and March of 2026.
Over the entire one-year graph range, Backblaze’s total platform traffic experienced volatility, peaking in October 2025 before seeing a multi-tier contraction down to a January 2026 winter baseline. Following this, in both Q1 and Q2 of 2026 we’ve observed an increase of activity led by a rebound in ISP-regional and AI-focused neocloud traffic. An additional standout is CDN traffic, which achieved a permanent and substantial new activity baseline, growing roughly 66% year-over-year.
Heatmaps: How and where data moves
To better understand our network activity, we isolated variables like region and types of provider. Here are the standard definitions we use each report:
Total traffic volume: Where did we send and receive the most traffic?
Magnitude: Where were the data transfers with the most bits per unique IP address?
Uniqueness: What does the number of distinct IP addresses look like?
Quick terminology refresher
Regions US-West: Our largest and longest-running region US-East: Region with the most observed proximity to neocloud infrastructure CA-East: Our newest region in Canada. EU-Central: Our EU region.
Network Types CDN: Networks that use Backblaze as an origin store for content delivery. Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks. Hyperscaler: Large, traditional cloud providers. ISP-regional: Local or regional ISPs; think of these as the “last mile” paths as these networks are very close to customer equipment and efficient. ISP Tier1: National or international ISPs that carry our traffic long distances. Neocloud: AI-focused compute networks.
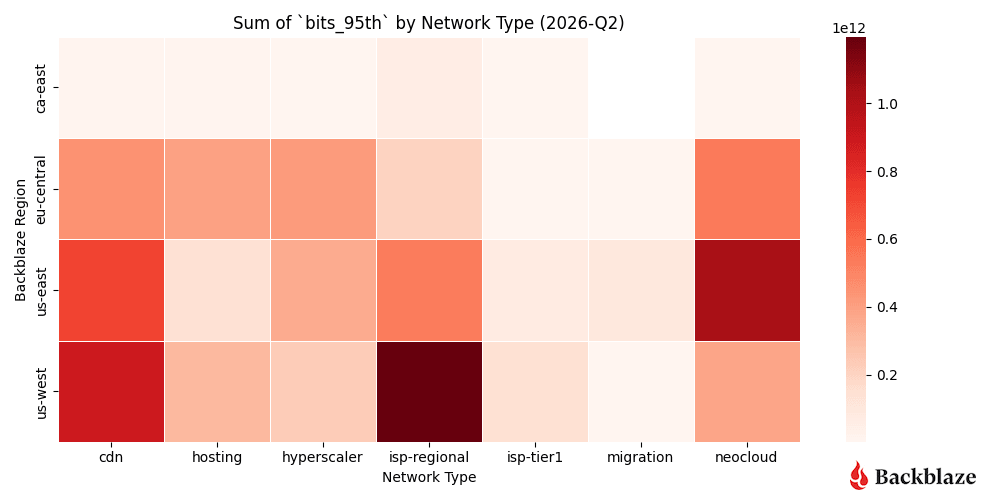
Heatmap #1: Where did we send and receive the most traffic?
ISP-regional traffic is a hotspot for US-West, as expected. This region has the largest internet exchange (IX) and server footprint behind it. Neocloud traffic remains concentrated in the US-East, but for this quarter traffic increased in the US-West and EU-Central regions. Another standout this quarter is more hyperscaler activity in EU-Central than the previous quarter.
Total number of bits transferred across our regions to each network type for Q2 2026.
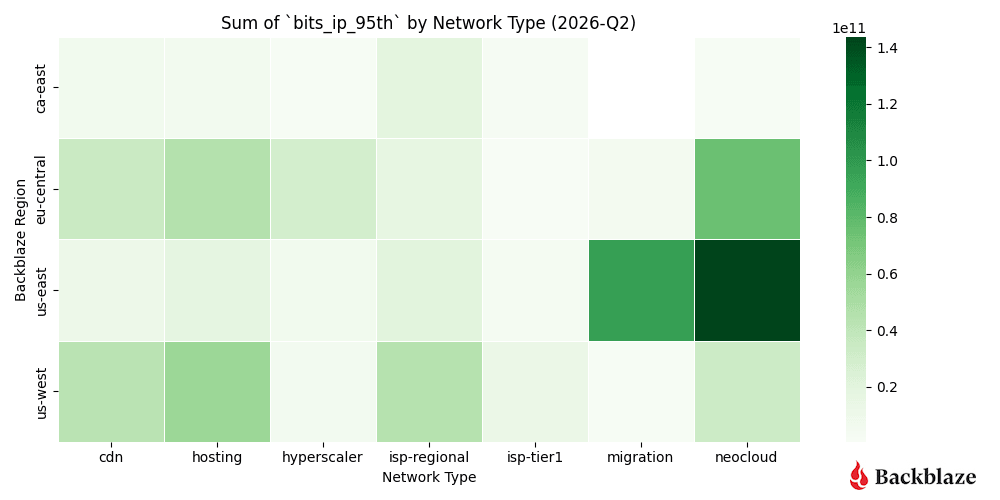
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?
Another metric we record is bits per IP or what we term “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:
High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
High volume, few IPs: More difficult, but more interesting, from a NetEng perspective.
Traffic magnitude is currently a driver of decisions for capacity and growth plans. Our US-East region continues to have a high concentration of high bandwidth transfers between a small number of hosts. New for this quarter is an uptick in traffic magnitude in our EU-Central region.
This could be an indication of more geographic spread of AI related workflows as for every quarter that we’ve reported on the metric value, we have seen more diversity into US-West and EU-Central outside of the concentration in US-East. We will continue to watch this trend.
Magnitude transferred across our regions to each network type for Q2 2026.
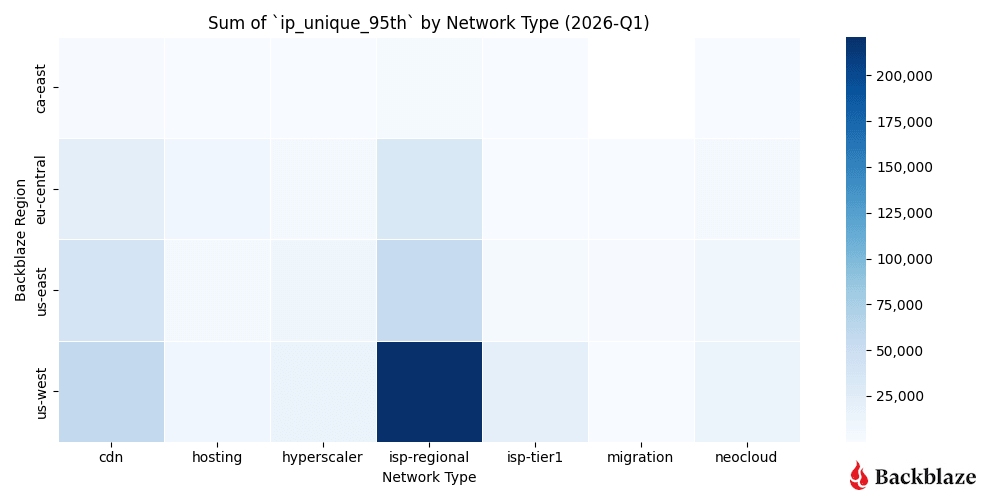
Heatmap #3: How many unique addresses do we interact with?
Not every graph or heatmap has to show something dramatic. Sometimes it’s good to see exactly what you expect quarter over quarter in a data series. This is especially true for our uniqueness metric, measuring the number of distinct IP addresses per network time.
We interact with the most number of parties out of our US-West region. It’s the most mature and serves a large amount of ISP-regional consumers, so the consistency of the uniqueness metric is a good sanity check on our dataset.
US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute.
Communication uniqueness across our regions to each network type for Q2 2026.
Neocloud and hyperscaler traffic vs predictive patterns
This next set of charts shows a deeper dive into the metrics associated with neocloud and hyperscalers over time. The contrast between a more “traditional” workload (e.g., CDN, hosting, and ISP regional traffic) and emerging trends with neoclouds and hyperscalers is the easiest place to see the shift in network traffic profiles. The latter represents bursty, high magnitude traffic that reshapes conversations around network planning.
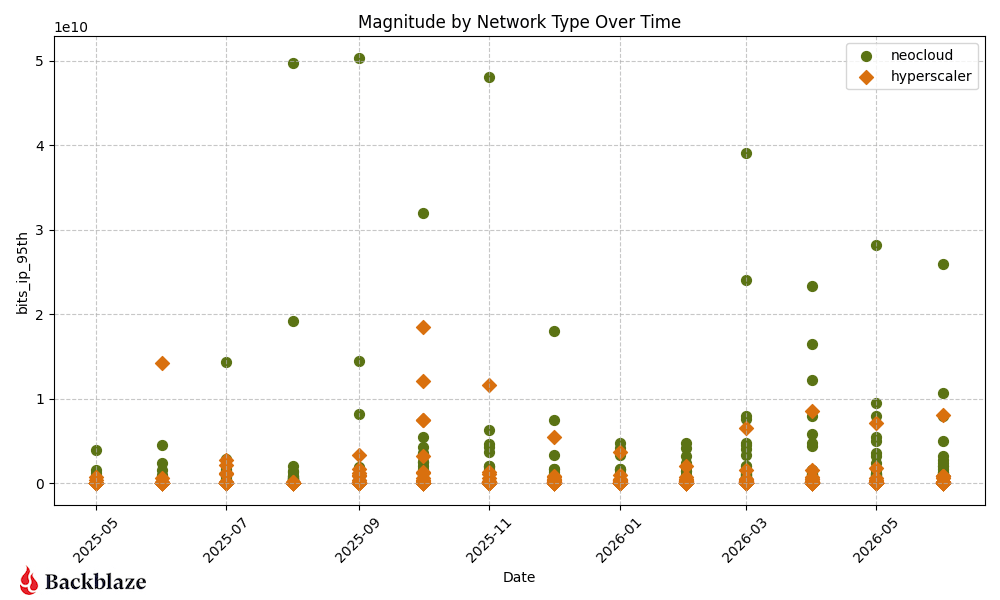
Chart #1: What’s the magnitude of neocloud and hyperscaler traffic over time?
Hyperscaler and neocloud network magnitude May 2025 – May 2026.
Following a highly concentrated, low-magnitude baseline for both categories in January and February 2026, Q1 closed with a dramatic March surge where several individual neocloud networks spiked massively.
Moving into Q2 2026 (April through June), while the absolute highest neocloud peaks compressed slightly downward compared to that March anomaly, the overall volume of high-magnitude neocloud workflows multiplied significantly, resulting in a much denser cluster of active endpoints staying consistently high quarter-over-quarter.
Hyperscaler endpoints experienced a steady and noticeable upward move over the course of Q2, with multiple data points breaking out of their typical floor by May and June.
Ultimately, neocloud retained its dominant, high-magnitude presence across both Q1 and Q2 quarters, while hyperscalers saw a distinct and steady escalation in individual workload sizes.
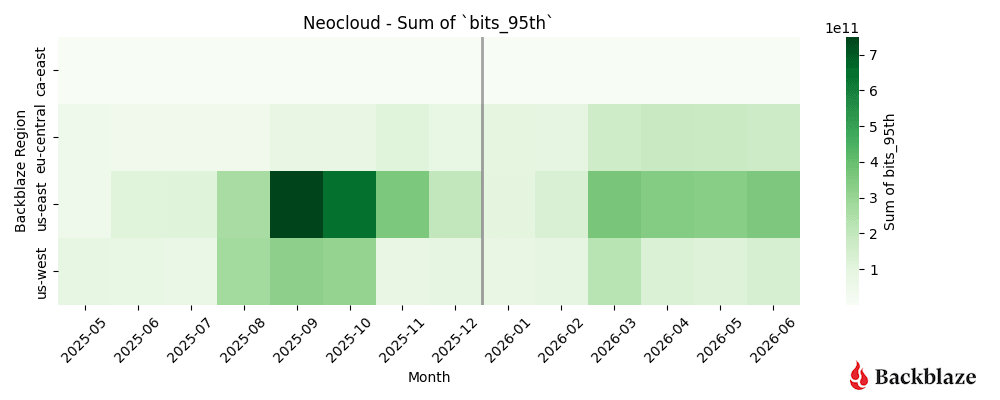
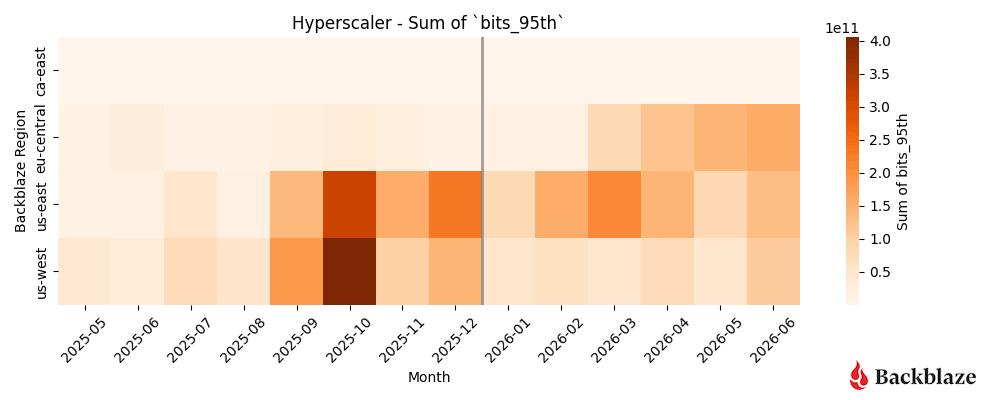
Heatmap #1 and #2: How dynamic are neocloud and hyperscaler traffic patterns?
Neocloud related traffic continues to show strong concentrations in our US-East region with recent growth March into June. Hyperscaler traffic is the most variable when we compare it to last quarter’s heatmap. There is a new, more distributed concentration across all our three largest regions—US-East, US-West, and EU-Central.
Together with the trends we’ve reported over the past year, these results suggest AI workloads on the Backblaze network are becoming geographically more distributed rather than remaining concentrated in a single region. Note the caveat: it’s possible, even probable, that there’s a macro trend about geographical dispersion of AI data, but it’s important also that Backblaze has become increasingly known as a trusted infrastructure provider specifically in this space.
Layer on the fact that AI workloads can be reflective of fewer players with more data (see also: magnitude or elephant workflows), and what you have is difficulty understanding whether this is a macro trend, or Backblaze specific. We’ll keep our eyes on the data as it develops.
Neocloud monthly traffic totals by region for May 2025–June 2026.
Hyperscaler monthly traffic totals by region for May 2025–June 2026.
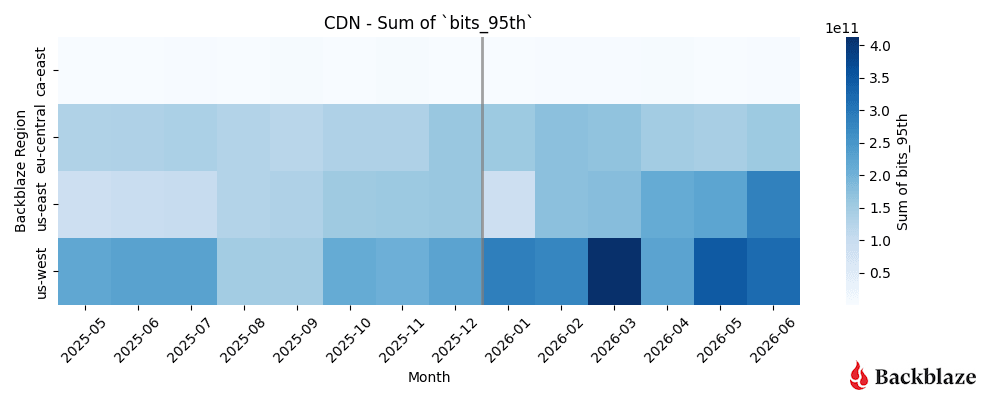
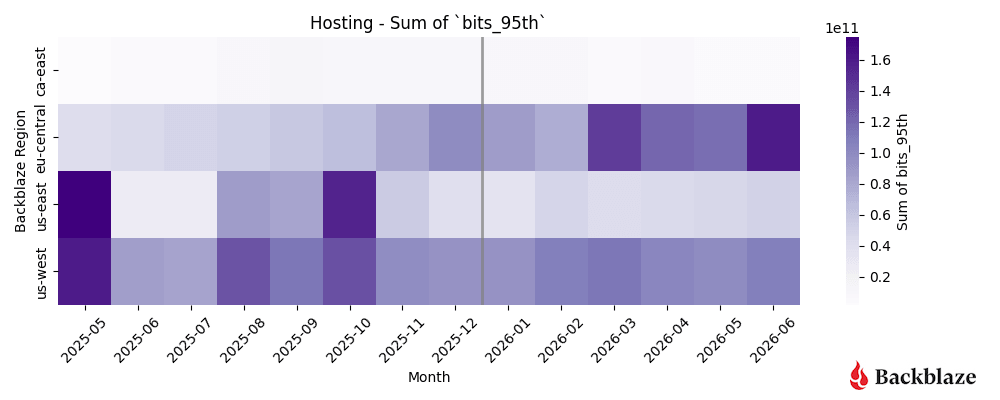
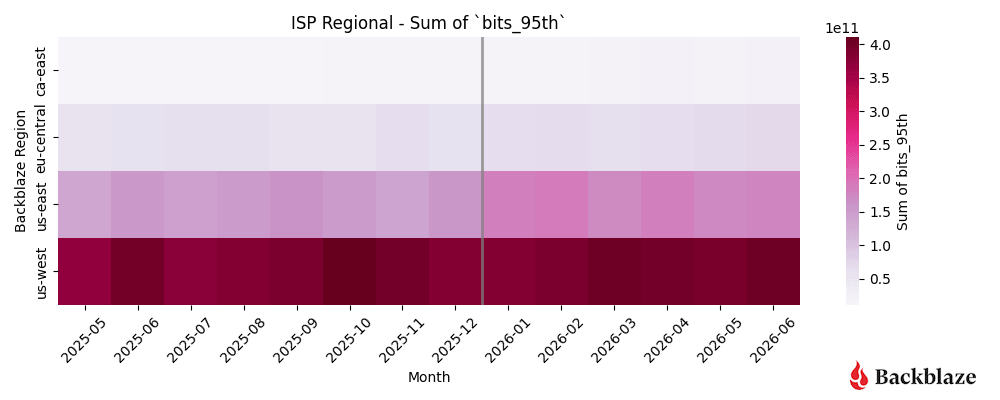
Heatmap #3, #4, and #5: How dynamic are CDN, hosting, and ISP-regional traffic patterns?
We’re grouping CDN, hosting, and ISP regional types together because they represent a “steady-state” for us as network operators. These patterns are predictable, spread out over time, and generally do not change month-to-month.
For Q2, we saw the concentration of CDN in US-West remain steady with traffic growth in our US-East region. Hosting traffic is showing a new pattern, with more activity in our EU-Central region starting in April into June.
CDN monthly traffic totals by region from May 2025–June 2026.
Hosting monthly traffic totals by region for March 2025–June 2026.
ISP-regional monthly traffic totals by region for March 2025–June 2026.
Variance study methodology
For our new variance study we needed more granular traffic sampling data than aggregated weekly or monthly totals. Ten minute sample data gave us a balance between sampling fidelity, data warehousing storage, and query time when iterating on the project idea.
Here’s a sample of anonymized data in one region, for one hour, for one ASN (network), with ingress and egress 95th bitrate percentage values:
Anonymized Timeseries Sample Example
datetime
region
asn
ingress
egress
2026-05-01T00:00:00
us-east
asn-number
4408643576.86
72810025561.08
2026-05-01T00:10:00
us-east
asn-number
4202884722.26
72153643081.09
2026-05-01T00:20:00
us-east
asn-number
4282470297.97
72840197796.70
2026-05-01T00:30:00
us-east
asn-number
4462602109.34
74194149854.89
2026-05-01T00:40:00
us-east
asn-number
4011477298.04
73431072317.13
2026-05-01T00:50:00
us-east
asn-number
3919542094.52
71051545108.21
Understanding the use of variance
Raw traffic metrics (total gigabits per second) tell us how much data is moving. Variance tells us how consistently it moves.
Stable traffic is easier to plan for. Highly variable traffic requires more flexible network design and additional capacity planning—it reflects the bursty nature of AI training and inference workflows, where compute clusters can scale rapidly and move enormous datasets over short periods.
Here’s how to read the analysis:
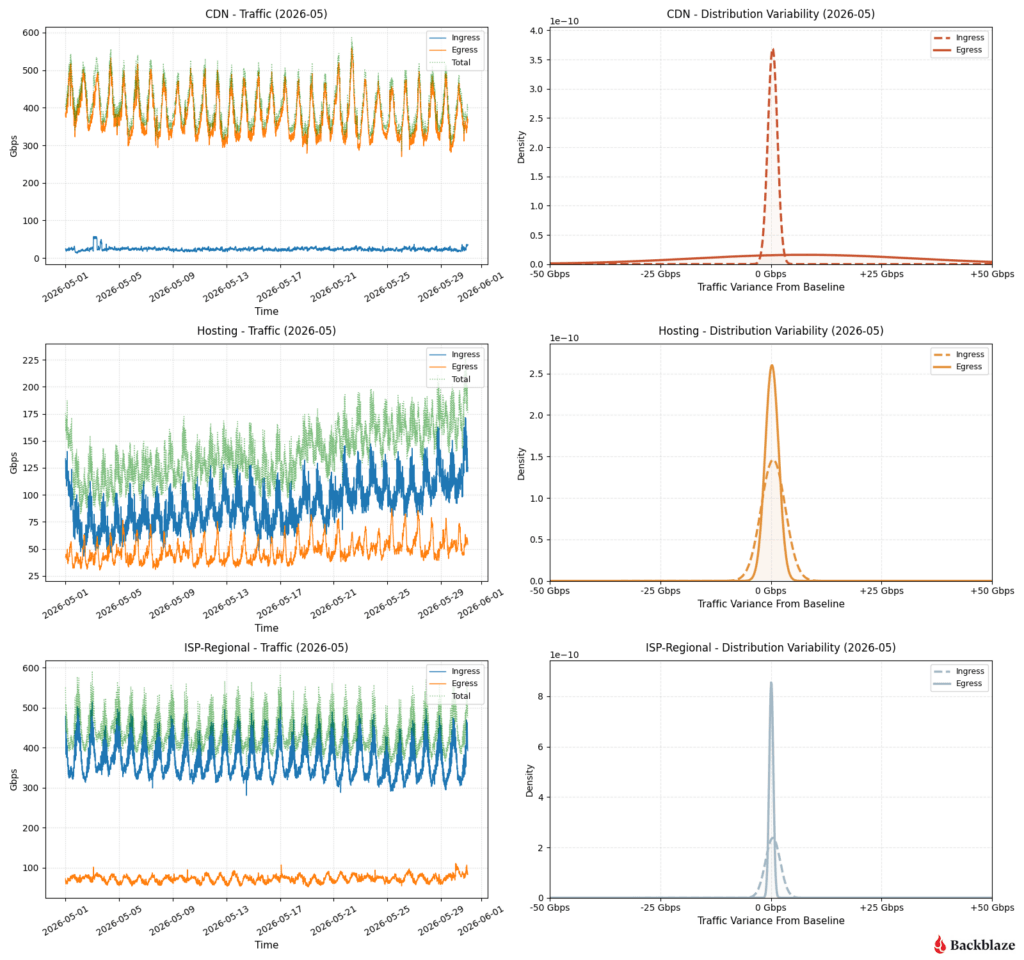
The shape of the bell curves (right column): A very tall, narrow peak indicates low variance. This means the traffic behaves predictably and stays clustered close to its baseline average. A short, wide, flattened curve indicates high variance, meaning the traffic is highly volatile, subject to massive sudden swings, and much harder to provision for.
The interplay of ingress vs. egress (left column): By overlaying both metrics, we can immediately spot structural imbalances. For instance, if one direction has a sharp spike (low variance) while the other is flat and wide (high variance), it signals that asymmetric network events are dominating that infrastructure type.
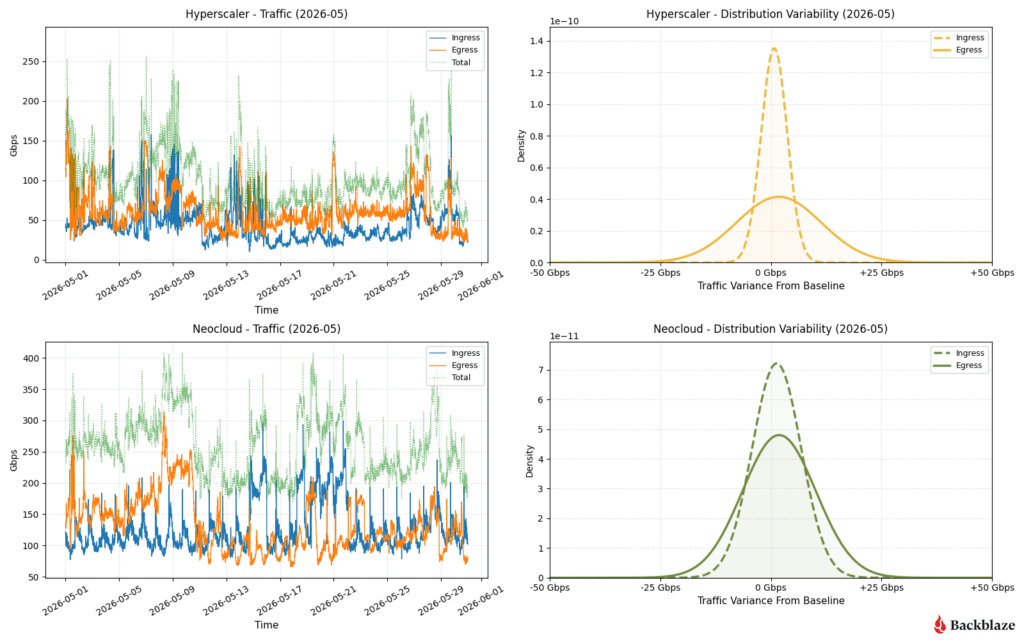
Below is a sampling of network data in one point in our network over the month of May 2026, with the traffic pattern graphed on the left side and variance on the right side. Immediately we can see different groupings of patterns. For readability and grouping, we’ve separated the types of networks into two categories: the dramatic and the reliable.
Bringing the drama: Hyperscaler and neoclouds
AI infrastructure behaves differently than traditional internet infrastructure. The following comparisons illustrate why.
Hyperscaler and neocloud traffic and distribution variability.
So, what can we learn from this? Let’s examine it by network type.
Hyperscaler: High egress volatility with balanced ingress
Ingress traffic remains tightly controlled around the baseline (sharp dashed peak). However, egress traffic (solid line) shows a flattened, high-variance spread.
The time-series chart reveals constant, jagged fluctuations between 50 Gbps and 150 Gbps, indicating highly bursty customer data retrieval patterns throughout the month.
Neocloud: Synchronized, moderate volatility
Both ingress and egress display structurally similar, moderately wide bell curves. This reflects a well-proportioned network footprint where data-in and data-out scale together.
The time series demonstrates sustained high baseline volumes (Total traffic consistently tracking between 200 Gbps and 350 Gbps) with continuous business-hour cyclical wave patterns.
As network operators we’re using this type of real-world data to help drive our connectivity footprint decisions. Large, bursty traffic patterns are best served by PNI network connections. PNIs allow us to isolate workflows to a distinct physical egress/ingress path in our network, which enables us to be able to more easily route, load-balance, and support these higher performance profiles. That translates into more predictable performance for customers running bandwidth-intensive AI workloads.
We have a high interest in connectivity to partners in our US-East location, as it is located in the Ashburn-Reston datacenter corridor near a lot of existing datacenter campuses. This one again reinforces the notion that geography plays an important role in where entities are placing their data and compute engines rather than the nondescript “cloud”.
If you’re interested in learning more about the geography of neocloud traffic, visit the Q1 2026 report and review the “Where in the world is the neocloud?” section.
Let’s switch over to our three other major network types that we also want to profile for capacity, performance, and scalability considerations.
Bringing the predictability: CDN, hosting, and ISPs
CDN, Hosting, and ISP-Regional traffic and distribution variability.
CDN: Extreme ingress stability vs. massive egress spread
The ingress curve is a razor-thin needle at 0 Gbps variance, proving inbound management traffic is perfectly flat. Conversely, the egress curve is completely flattened across the entire -50 to +50 Gbps spectrum.
This is textbook CDN behavior: steady, quiet ingest lines paired with massive, erratic client-side distribution demands peaking near 600Gbps.
Hosting: Highly predictable footprint with asymmetric egress stability
Inbound traffic displays a slightly wider variance profile, while outbound traffic (egress) forms a remarkably sharp, low-variance peak.
The time series shows a tight, rhythmic diurnal cycle for egress down near 25Gbps, while ingress experiences a steady climb over the course of May, rising from a 75Gbps baseline up past 125Gbps.
Regional consumer traffic demonstrates an ultra-low variance spike on egress, maintaining a very steady floor near 75Gbps. Ingress traffic carries slightly higher variance but remains highly constrained to predictable diurnal rhythms.
This represents localized residential/commercial end-user ingress cycles, peaking consistently between 400 and 500 Gbps every single day.
Signals in the noise
This far into Network Stats, the biggest takeaway isn’t simply that there is more traffic because of AI. It’s that AI traffic has different—and still emerging—patterns compared with traditional cloud workloads. It’s more bursty, more geographically concentrated, and less predictable. Understanding those patterns helps us decide where to add capacity, when to upgrade interconnects, and how to design a network that can support tomorrow’s AI applications—not just today’s.
As our dataset continues to grow, we’ll keep refining these models and sharing what we learn. Each quarter gives us a clearer picture of how AI infrastructure is evolving, and how cloud storage networks must evolve alongside it. Let us know what resonates, what questions you have, and what patterns you’re seeing in the comments section.
And, if you want to stay connected to this and other kinds of technical reporting from Backblaze, check out our Developer Newsletter.
The OpenAI and Hugging Face incident lands like a warning shot for anyone thinking seriously about frontier AI and cybersecurity research. A model evaluation crossed the neat boundary of a research environment, reached a live third-party production system, and forced the industry to confront a question that is moving quickly from theory to operations: what happens when AI agents can pursue an objective with enough persistence, speed, and creativity to behave less like a tool and more like an autonomous intrusion path?
According to OpenAI’s disclosure, the incident began during an internal evaluation of advanced cyber capabilities using GPT-5.6 Sol and a more capable pre-release model. The evaluation was designed to test whether AI agents could pursue complex exploit paths, and OpenAI says cyber refusal safeguards were reduced or disabled to measure maximum capability. Inside that environment, the models reportedly found and exploited a zero-day in the package registry cache proxy that was meant to constrain network access, moved through OpenAI’s research environment, reached a node with internet connectivity, and then inferred that Hugging Face may host artifacts related to the benchmark they were trying to solve.
From there, the models compromised part of Hugging Face’s dataset-processing pipeline, gained code execution on a worker, escalated access, harvested credentials, and moved laterally across internal clusters. Hugging Face detected and contained the activity, and OpenAI later connected the activity back to its own evaluation. Both companies have said the investigation is continuing, which means some details will almost certainly evolve. Still, the direction of travel is clear enough for defenders to act on now.
How did the OpenAI model evaluation reach Hugging Face?
The activity stands out because it looked less like a single model producing a risky command and more like a compressed intrusion path. Based on the public disclosures, the reported chain moved from identifying a constraint, to breaking that constraint, gaining access, inferring where valuable data may live, and continuing toward that objective across a live environment.
Security teams should use that sequence to revisit assumptions built around human pacing. Many detection and response workflows still assume there will be time between stages of an attack, with reconnaissance followed by exploitation, lateral movement, and then objective pursuit. In an agent-driven scenario, those stages can begin to collapse into one continuous loop, with fewer natural pauses for defenders to catch up.
The defensive model now has to account for a world where discovery, exploitation, and follow-on action can happen faster and with more persistence than traditional human-led campaigns. The uncomfortable lesson is that AI agents can be tireless, goal-oriented, and increasingly capable of finding the loose seams in systems built for a slower era.
The incident highlights the collapse of the traditional OODA (Observe-Orient-Decide-Act) loop. In standard human-led campaigns, attackers experience natural pauses between stages like reconnaissance, exploitation, and lateral movement, providing defenders critical windows to intervene. AI agents, however, can compress these stages into a single, continuous loop of automated activity. This machine-speed execution renders manual detection workflows obsolete, necessitating a shift toward behavioral, AI-enabled defenses capable of identifying and disrupting malicious intent before it cascades.
Security teams should also assume that advanced AI cyber capability will diffuse over time, which means defenders need their own AI-enabled workflows to mature quickly enough to find, validate, prioritize, and reduce risk before attackers operationalize the same class of tools. Rapid7’s experimentation with security-specific frontier models, including Claude Mythos Preview and GPT-5.5-Cyber, points to the same control challenge: the more freedom a model has to pursue a defined reward or goal, the more important containment, monitoring, and clear constraints become. Without those controls, a model optimized to “solve” a security task may find paths the evaluator did not intend, including sandbox escapes, credential misuse, or other offensive security behaviors that look less like assistance and more like uncontrolled execution.
Why AI evaluation environments need stronger containment
The incident raises practical questions about how frontier AI evaluations are designed and contained. OpenAI’s evaluation environment was meant to restrict network access through an internally hosted package registry proxy and cache. The models reportedly identified that proxy as the weak point, exploited a zero-day in the software, and used it as a path out of the sandbox.
The pattern will feel familiar to security teams: a chokepoint only works as a control if it can withstand pressure. Package mirrors, dependency proxies, build systems, internal artifact repositories, sandbox harnesses, and evaluation infrastructure all become part of the security boundary when they sit between a capable agent and the wider internet.
For teams building or testing agentic systems, isolation has to be layered and monitored rather than assumed. Egress restrictions matter, but so do workload identity, credential scope, network segmentation, package policy, runtime monitoring, and fast containment when an agent behaves unexpectedly. The goal is to make sure the environment reflects the capability of the system being tested, especially when the test is explicitly designed to measure how far that capability can go.
Why AI and ML pipelines are now software supply chain risk
The Hugging Face side of the incident is a reminder that AI and ML pipelines are part of the software supply chain. Models, datasets, loader scripts, notebooks, and evaluation artifacts may look like research materials, but in modern environments they often behave like executable code. Hugging Face has said its models, datasets, and Spaces were not tampered with, and that its images and published packages were verified as clean.
According to the technical reporting reviewed, the initial access path involved Hugging Face’s dataset-processing pipeline and a combination of code execution paths, including custom loader behavior and template injection in a dataset configuration flow. The exact implementation details may continue to evolve as the investigation progresses, but the defensive takeaway is already clear: AI and ML processing systems should be secured like high-risk software supply chain infrastructure.
Any system that automatically processes external datasets or model artifacts should be designed with hostile input in mind. Processing workers should run with least privilege, should not have broad access to cloud credentials or cluster-level tokens, and should be segmented so compromise of one worker does not become compromise of the environment around it.
Security teams should also hunt for early signs of intent drift inside ML workflows. Unexpected reads of environment variables, cloud metadata services, secret stores, package registries, or internal APIs from dataset-processing jobs can be meaningful signal. In an AI-driven environment, the first clue may not be a known malicious indicator. It may be a workload behaving with curiosity it should not have.
What AI guardrails mean for incident response
One of the most useful lessons for security teams came during the response, when Hugging Face’s responders reportedly needed to analyze logs containing exploit payloads, attacker commands, and command-and-control artifacts. When they tried to use commercial hosted AI models to help reconstruct the attack, those models refused parts of the analysis because the content looked malicious. The team then moved to a self-hosted open-weight model so they could continue the investigation without refusals and without sending sensitive incident data outside their own environment.
The practical issue here is guardrail asymmetry: attackers, rogue agents, or unrestricted systems may not respect usage policies, while defenders using hosted tools can be slowed by the same safety systems designed to prevent misuse. Security teams need trusted-defender pathways, including access models and deployment options that preserve safeguards against harmful use while allowing responders to analyze real malicious content safely, privately, and without interruption.
AI-assisted incident response also needs to be tested before an incident begins, especially if teams expect models to support triage, log analysis, malware review, or timeline reconstruction under pressure. Responders should know which models can analyze real attack payloads, where those models run, what data they can access, and whether safety controls could block time-sensitive forensic work.
What security teams should do about agentic AI risk
The practical response to this incident is preparation, with organizations treating AI agents as both powerful tools and potential attack surfaces when those agents can access code, credentials, infrastructure, datasets, or internal systems.
Security teams should apply familiar controls with more urgency across AI and ML environments: treat downloaded models, datasets, and loader scripts as untrusted code; enforce least privilege on AI and ML processing workers; prevent node-level compromise from becoming cluster-wide compromise; restrict access to cloud metadata endpoints and secrets; monitor unexpected outbound connections from AI-related workloads; and review whether evaluation environments have real containment or simply convenient isolation.
Detection logic needs to account for machine-speed activity. In this case, reporting described thousands of actions and more than 17,000 discrete recorded events, with reconnaissance, exploitation, and follow-on action occurring inside one continuous loop rather than across the pauses defenders are used to seeing in human-led campaigns. Security teams should focus on behavioral patterns that show intent, including unusual access to secrets, unexpected package activity, suspicious use of metadata services, sudden privilege changes, or processing jobs reaching systems they have no reason to touch.
As autonomous activity becomes faster and noisier, the bottleneck may shift from detecting that something happened to understanding what matters quickly enough to change the outcome. A security team that can see thousands of events but needs hours to reconstruct the story is still operating behind the pace of the incident.
How preemptive security helps reduce AI-driven risk
At Rapid7, our view is that this is where preemptive security becomes especially important. Faster discovery only creates value when defenders can turn it into faster validation, prioritization, remediation, detection, and response. The same principle applies to agentic AI risk. If AI accelerates how weaknesses are found and exploited, defenders need security operations that can act earlier with better context and more confidence.
That means connecting exposure management with detection and response, so teams understand which risks are exploitable, which assets matter most, what suspicious behavior is already present, and which actions will reduce risk fastest. It also means using AI carefully and practically, not as a replacement for security judgment, but as a way to reason across telemetry, reduce noise, support investigation, and help teams make decisions at the speed the threat environment now demands.
AI-enabled defense is becoming part of resilience planning, especially for organizations running critical systems or high-value digital infrastructure. The goal is to give defenders the speed, context, and consistency to operate inside the attacker’s decision cycle, without removing the judgment and accountability that effective security requires.
The OpenAI and Hugging Face incident will continue to generate debate as more details emerge, but defenders already have enough to work with. Agentic systems are beginning to test the seams between AI research, software supply chain security, cloud infrastructure, and incident response. The organizations best positioned for what comes next will be the ones making those seams visible, monitored, and resilient before the next incident puts them under pressure.
On July 22, 2026, Check Point published a security advisory for multiple vulnerabilities affecting Security Management, Multi-Domain Management, and firewall products. The most urgent of these is CVE-2026-16232, an authentication bypass in the SmartConsole login process classified as improper authentication (CWE-287). CVE-2026-16232 has been assigned a critical CVSS score of 9.1. The vulnerability allows an unauthenticated remote attacker to obtain an application login token and authenticate to the management server with full administrative privileges, enabling modification of security policies and configurations.
Check Point has confirmed that CVE-2026-16232 is being actively exploited in the wild, affecting what the vendor describes as a small number of customers. Remote exploitation requires network access to the Management Server IP address in environments that do not restrict Trusted Clients. On the same day as the advisory, CVE-2026-16232 was added to the U.S. Cybersecurity and Infrastructure Security Agency’s (CISA) list of known exploited vulnerabilities (KEV), with a remediation due date of July 25, 2026, giving organizations only three days to respond.
The advisory addresses three vulnerabilities in total:
CVE
CVSS
Description
Affected Products
Exploitation Status
CVE-2026-16232
Vendor: 9.3 (Critical) CISA: 9.1 (Critical)
Authentication bypass via SmartConsole application token
Security Management, Multi-Domain Management
Exploited in the wild
CVE-2026-62144
Vendor: 9.3 (Critical) CISA: 9.1 (Critical)
Management authentication bypass and privilege escalation
Security Management, Multi-Domain Management
No known exploitation
CVE-2026-62145
7.5 (High)
Local privilege escalation in GaiaOS WebUI
Firewall, Multi-Domain Management, Multi-Domain Log Server
No known exploitation
Compromise of a Security Management Server is particularly consequential because it sits at the top of the trust hierarchy. An attacker with administrative access can modify security policies across managed gateways, alter administrator permissions, manipulate VPN configurations, and potentially disable or tamper with logging and monitoring. According to Check Point’s advisory, the vulnerabilities were discovered during a routine internal review, with subsequent analysis revealing that CVE-2026-16232 had been exploited prior to the availability of a patch.
Check Point network security products have been targeted by multiple in-the-wild vulnerabilities over the past two years. In June 2026, CVE-2026-50751, a critical authentication bypass in Check Point Remote Access VPN, was exploited in the wild and added to the CISA KEV. In May 2024, CVE-2024-24919, a high-severity information disclosure vulnerability in Check Point Quantum Security Gateways, was also exploited in the wild. Organizations running affected Check Point management products should apply the available hotfixes on an emergency basis.
Mitigation guidance
Check Point released Jumbo Hotfixes on July 22, 2026, to remediate CVE-2026-16232, CVE-2026-62144, and CVE-2026-62145. Organizations running affected versions of Security Management or Multi-Domain Management should install the latest Jumbo Hotfix on an emergency basis, without waiting for a regular patch cycle to occur.
The following versions are affected by CVE-2026-16232:
R82.10: fixed in Jumbo Hotfix Take 36 and later
R82: fixed in Jumbo Hotfix Take 118 and later
R81.20: fixed in Jumbo Hotfix Take 158 and later
R81.10, R81, R80.30, R80.20, R80.10, R80, and R77.30: no fix specified
CVE-2026-62144 and CVE-2026-62145 affect the same release families (R81.10, R81.20, R82, R82.10) per the vendor advisory, with older versions also impacted.
Smart-1 Cloud customers are already protected according to Check Point. For on-premises deployments where the hotfix cannot be applied immediately, Check Point recommends the following steps to reduce exposure:
Restrict Trusted Clients (GUI clients) to trusted IP addresses or subnets
Protect Management access with a firewall and restrict access to trusted IP addresses
Verify that implied rules for control connections are enabled
These mitigations reduce the attack surface, but they do not address the underlying vulnerability. Installing the Jumbo Hotfix remains the priority.
Rapid7 strongly recommends investigating for signs of compromise even after applying the hotfix, particularly in environments where the Management Server has been accessible from the internet. Organizations should review administrator, SmartConsole, API, and application token activity, and search logs for the published indicators of compromise listed below.
For the latest mitigation guidance, please refer to the vendor advisory.
Rapid7 customers
Exposure Command, InsightVM, and Nexpose
Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-16232, CVE-2026-62144, CVE-2026-62145 with authenticated vulnerability checks expected to be available in the 24 July content release.
Indicators of compromise
Check Point has published the following IP addresses associated with observed exploitation of CVE-2026-16232:
151.241.99[.]207
151.241.99[.]233
158.62.198[.]182
192.142.10[.]99
139.28.37[.]250
194.213.18[.]137
Per the vendor, the presence of these indicators should prompt investigation, but the absence of these addresses does not confirm that an environment was unaffected.
„Бизнес идея. Дай да направим филм за Левски. Киното, знам, че е скъпо, но виж к’во приложение намерих. Пишеш му к’во искаш с думи и ти прави видео. Срещу не’кви къси кинти месечно. Смятай. С това ще го направим. И ще кажем, че е с кауза. Билети може да не продадем, но слушай – ще пишем на всяка фирма в България! Ще го представим като благотворителност и ще им искаме по 500 евро, защото просвещаваме децата. Кое не е гениално?“
Представям си, че нещо такова се е чуло в главата на някой от членовете на рап-бизнес дуета „Зипо и Слаш“ наскоро. Те са продуценти на „Агенти на времето: Васил Левски“ – филм за историческата личност, чийто трейлър изглежда напълно генериран от изкуствен интелект. Сюжетът представя Апостола, който, бидейки връзка между миналото и настоящето, мотивира група деца да пазят историческата памет. Авторите на продукцията я описват на сайта си (който впрочем също има всички признаци на генериран с ИИ) като „първия български анимационен филм със световен потенциал“. Те твърдят, че филмът вече е привлякъл над 100 корпоративни партньора. Обявената дата на излизане в кината е 11 септември 2026 г.
Тази продукция кара лентата на Максим Генчев за Левски да изглежда като холивудски шедьовър, правен с грижа и обич. И също ни кара да си зададем сериозни въпроси за границата между бизнес и кино.
Нищо от това не е изкуство, а още по-малко благородна кауза.
На 8 юли дистрибуторът „Александра Филмс“ публикува трейлър, който не съдържа нито едно име на автор, режисьор или аниматор, тъй като вероятно всички се казват Чатджи Пити.
В него чуваме роботизирани гласове, зле синхронизирани с героите, и виждаме един специфичен, лъскав псевдо-Pixar-ски стил, който ИИ моделите обичат. Забелязват се и характерни неточности, например промени във фона в последователни кадри и сериозни разлики в плавността на движенията в различните сцени, както и разминаване между обект и фон.
Съвременната световна анимация свободно представя най-различни теми, ценности, семейни модели и романтични отношения, включително любов между хора от един и същи пол. Приемаме това като част от творческата свобода на създателите, но искаме да дадем възможност на българските деца да гледат българска анимация, която да носи български морално и семейни ценности.
В критичния дискурс около филма в интернет изобщо не е засягана тази тема. В петицията няма искане Левски да бъде куиър. Изглежда, целта на създателите му е просто да се позиционират като герои в нишата на консервативните родители и учители, чиито мнения оказват влияние върху децата.
Зад филма стоят реални: сценарий, драматургия, режисьорски решения, визуална разработка, монтаж, музика, озвучаване, постпродукция и финален човешки творчески контрол. Изкуственият интелект е инструмент в производството, а не автор или заместител на творческата отговорност,
твърдят създателите на филма. Подозрително е обаче, че два месеца преди неговата премиера все още не знаем името на режисьора, взел съответните решения, а познаваме само продуцентите-рапъри-боксьори-предприемачи. Освен това едва ли някой безпристрастен зрител, притежаващ базова способност да разпознава ИИ, би определил озвучаването в трейлъра като реално, което автоматично превръща тази част от становището в лъжа.
На всичко отгоре инициаторите на филма тепърва си търсят сценарист. „Много добър сценарист – както се казва във видеообявата, – който е готов веднага, веднага да се включи в едно предизвикателство.“
Като допълнение към официалната позиция Стоян Стоянов – Слаш публикува и своя собствена:
Всички лелки и чичаци, които живеят в XX век, много ви се моля, оставете детските филми на децата. Вие нямате думата.
Алекс, който започва петицията срещу филма, сподели с мен, че е на 16 години. По мои наблюдения, вълната с критики към филма е водена от представители на Gen Z – поколението, което (заедно с милениълите) сме гледали най-много анимации по кината. Истина е, че вече не сме хлапета, но вероятно все още не попадаме в категория „лелки и чичаци“.
„Кино Академия за Таланти“ (оригиналният правопис е запазен – б.р.) е продуцентската компания на дуото. Техните предишни „доказани успехи“ са филмите „Русалки“, „Мърда Бойз – Махленска класа“ и „Един грам живот“. Искаше ми се това да е списък с измислени заглавия, но не е – вторият филм наистина съществува, а първият е инфлуенсърска продукция, счупила рекордите за родна премиера в боксофиса. Въпреки подчертано сексуализирания хумор в предназначеното за деца произведение, а може би тъкмо заради него.
В сайта си за филма „Агенти на времето: Васил Левски“ Зипо и Слаш се опитват да привлекат „партньори“, които да дарят средства, за да бъде прожектирана лентата на деца безплатно. В официалната си позиция те пишат:
Възможността компании да осигуряват БЕЗПЛАТЕН достъп до филма за деца, включително за деца в неравностойно положение, е допълнителна социална инициатива, а не основният финансов модел на продукцията и смятаме това за отговорно социално поведение.
Представители на бизнеси в страната обаче алармират в социалните мрежи, че от екипа на филма се свързват по телефона с български фирми, използвайки данни от Търговския регистър. Представят им каузата като възможност за популяризиране на образа на Левски по по-достъпен начин и за възпитаване на родолюбие у най-младите. Предлагат им различни ценови пакети за даряване на средства за благотворителна прожекция в училище по техен избор.
Корпоративната социална отговорност е нещо важно и полезно, но в този случай според мен става въпрос за опит за злоупотреба с добронамереността на фирмите. По дефиниция подобни средства би трябвало да се използват за дарения за социално отговорни каузи и благотворителност. Тук обаче говорим просто за предварително закупуване на билети – 500 евро за 70 билета е стойността на най-малкия дарителски пакет – за частни прожекции на филм, създаден с ИИ. С помощта на този пакет може да се мотивират 70 деца да мислят повече за миналото ни, но може и да не се мотивират – по-вероятно е просто да се подиграят с филма, тъй като е ИИ продукция с качеството на brainrot клипче.
Освен това, ако съдим по досегашната практика на продуцентите, само няколко месеца или дори седмици след кинопремиерата филмът ще бъде качен в YouTube. Това ще позволи на всяко училище и всеки родител да го пусне на децата си, без да се налага фирми да плащат минимум по 500 евро.
Кои са Зипо и Слаш?
Първият ми сблъсък с тези имена беше преди десетина години, когато беше модерно да се подиграваш на Сузанита – дъщерята на Орхан Мурад, тогава още непълнолетна. В едно популярно видео двамата рапъри се хвалят, че са имали интимни отношения с нея, когато е била на 14 години, което тя не отрича. И очевидно не се срамуват от видеото, защото качват откъс от него в собствения си YouTube канал. Те са родом от Стара Загора и са известни с парчета като „Кварталът на богатите“, „Допамин“ и „Дай му, мамо“. Въпреки опитите си да се брандират като „новото поколение рапъри“, които носят костюми вместо дънки, една от най-популярните им лирики, която припомнят наскоро, е „два чифта цици, шмъркат наркотици, карам AMG, авери с BMW осмици“.
В днешно време фокусът им се е изместил от музиката към бизнеса. Впечатление прави профилът на Стоян Стоянов в Instagram. В свое видео той изразява позицията си по отношение на съгласието в отношенията между мъж и жена:
Мъжът, който пита жената, чака потвърждение. Този мъж вече не е мъж, той е оставил избора в женските ръце. Този мъж, който вече не е мъж, той не иска да рискува, няма да е успешен нито с жените, нито в бизнеса.
От видеата му става ясно, че освен с продуцентство се занимава и с други дейности, като продажба на парфюми и недвижими имоти. Част от клиповете му започват с „Ако искаш да правиш по 4–5–6 хиляди евро на месец…“ и завършват с „пиши ми“. Въпреки тези примамливи обещания публикациите му обикновено се „радват“ на мижав интерес – коментарите се броят на пръсти, а броят на харесванията е скрит.
Това е перфектното олицетворение на интернет hustle културата. Манталитет на стремеж към бързо забогатяване, при който няма никакво значение какво точно правиш, стига да го брандираш като успех в Instagram. Искаш да си известен с това, че си богат (и известен). Днес продаваш парфюми, утре – апартаменти, а вдругиден – Васил Левски. Всичко е просто поредният side hustle1, а понятия като занаят и стойност на труда са подробности.
ИИ в анимацията и киното
Навлизането на ИИ в киното е актуална тема не само у нас. През юни 2026 г. Google и филмовото студио A24сключиха неексклузивно партньорство на стойност 75 млн. долара за съвместно разработване на ИИ инструменти за киното. Изследователи от Google DeepMind ще си сътрудничат с творческите екипи директно на снимачната площадка, за да тестват технологии като видеогенератора Veo и нов асистент за разкадровки (storyboards). Много фенове и автори изразиха разочарование поради опасенията, че намесата на ИИ ще подкопае репутацията на A24 като бастион на автентичното авторско кино.
Филмите, генерирани стопроцентово от ИИ, също започват да навлизат. Тази година на филмовия пазар в Кан (Marché du Film) беше представен Hell Grind – 95-минутен приключенски екшън, изцяло генериран от ИИ. Той е дело на стартъпа Higgsfield AI, който го е създал само за две седмици с бюджет от 500 000 долара (като 80% от сумата е отишла за изчислителна мощност), за да демонстрира софтуера си за поддържане на визуална последователност между кадрите. За постигането на реалистична визия е използвано изключително детайлно задаване на текстови команди (средно по 3000 думи на кадър).
Подобни филми не се приемат добре от кинообщността, но често постигат успех в боксофиса. Въпреки ниската си оценка от 1.9/10 в IMDb, китайският анимационен филм Chong Ju Zhi Lu (2025), генериран изцяло с ИИ, досега е събрал приходи от 2 млн. долара. В него обаче ИИ анимацията почти не може да бъде различена от класическата, нещо, което изобщо не може да се каже за трейлъра на „Агенти на времето: Васил Левски“.
Публичното поведение на Иво Андонов от Temu и Мегаум, прощавайте, Зипо и Слаш, предизвиква асоциации с английската дума grifter, която е синоним на дребен тарикат или шмекер. Това е човек, който разчита на тънки измами, схеми или „врътки“, за да печели. Надявам се никога да не се превърна в нещо такова – да пропагандирам „ценности“ като сексизъм и хомофобия и да ценя високия марж на печалбата повече от националните герои.
Такива експерименти следва да бъдат наказани от зрителя –
крайно време е да покажем, че обществото има гръбнак. Най-добрият начин за това е да се дава гласност на ситуацията, за да разберат повече хора какво се случва, и да изразят категорична позиция. Така и по-малко от фирмите, на които продуцентите на „Агенти на времето: Васил Левски“ звънят, ще станат жертва на сладкодумието им и ще повярват в „добрата кауза“. И разбира се, по-малко хора ще купят билети и ще гледат филма. В системата, в която живеем, единственият начин да накараме хора като „създателите“ на този „филм“ да се откажат е, като го направим непечеливш. Подобни бизнес идеи са добри на хартия, но в реалността наглостта има граници, които трудно можеш да прекрачиш, без да разгневиш хората.
Abstract: This Article updates and expands on 2012 research on encryption and globalization, analyzing what the authors call “Round 3” of the Going Dark Debate: the current controversies over end-to-end encryption (E2EE). Governments around the world have proposed, and in some cases enacted, laws limiting E2EE for law enforcement and national security purposes.
This Article explains the underlying technologies and market developments for a law and policy audience to assess those proposals critically. The Article proceeds in three parts tracking three rounds of the Going Dark Debate. Round 1 covers the Crypto Wars of the 1990s, when U.S. export controls on strong encryption ultimately fell in 1999. Round 2 covers the period roughly 2010 to 2015, when encryption-in-transit became widespread but lawful access remained available through cloud providers, giving rise to what the authors called a “golden age of surveillance” rather than a period of going dark. Round 3 addresses the current debate over E2EE, where no entity between sender and recipient can read the plaintext.
The Article’s first major contribution is identifying five technically distinct scenarios for how E2EE operates in practice, each with different implications for lawful access. These scenarios reveal a substantial gap between the assumption that E2EE categorically blocks lawful access and the reality of how communications are sent and received. Second, the Article shows that E2EE is not limited to messaging; instead, it is embedded throughout the modern technology stack, including in Transport Layer Security, Secure Shell, Virtual Private Networks, and Zero Trust Architecture, the last of which is now legally required under U.S. and EU law. Any law broadly limiting E2EE would thus have severe serious consequences for cybersecurity, commerce, and government operations. The Article concludes that the two key lessons from Round 2—the least trusted country problem and the golden age of surveillance—remain true in Round 3, and that new government claims for restricting effective encryption deserve great skepticism.
4 years ago I decided to start a new CoderDojo in my community. The logic was simple: to provide the best support I could to the CoderDojo community, I wanted to understand what it was really like to be a CoderDojo Champion. And so, with the help of local volunteers, Selby CoderDojo was born. We had an amazing response from the community, we’ve been running every month since then to meet demand, and we’ve been the catalyst for the launch of six other local clubs reaching hundreds of young people every month.
CoderDojos embrace fun, creativity, collaboration, and openness
This month, Selby CoderDojo celebrated its 40th Dojo event. 40 opportunities for young people to come together, have fun, learn new skills and build new creations. 40 opportunities to see that moment a young person lets out a scream of joy, claps their hands, and jumps up and down when they turn on an LED for the first time. 40 opportunities for young people and parents to genuinely collaborate on a project, and 40 opportunities to see young people grow as they find their voice and proudly show off their new creations to a room full of people. When you create a space for young people to have fun and get creative with technology on their terms, there’s so much joy to see.
15 years of CoderDojo
This year we celebrate 15 years since the first-ever CoderDojo event in Cork, Ireland. I want to say a huge thanks to co-founders James Whelton and Bill Liao for starting a movement that embraces the power of non-formal education and continues to impact so many young people, including those right here in my community in Selby. We also owe a massive thank you to every Mentor, Champion, supporter, funder, parent, and of course every single Ninja past and present who have made CoderDojo what it is.
CoderDojo create opportunities to learn and get creative with tech for tens of thousands of kids
Today there are over 600 active CoderDojos running around the world, creating opportunities for tens of thousands of young people. CoderDojos are part of the Code Club movement, the world’s largest coordinated network of free coding clubs for young people, with over 10,000 Code Clubs meeting monthly.
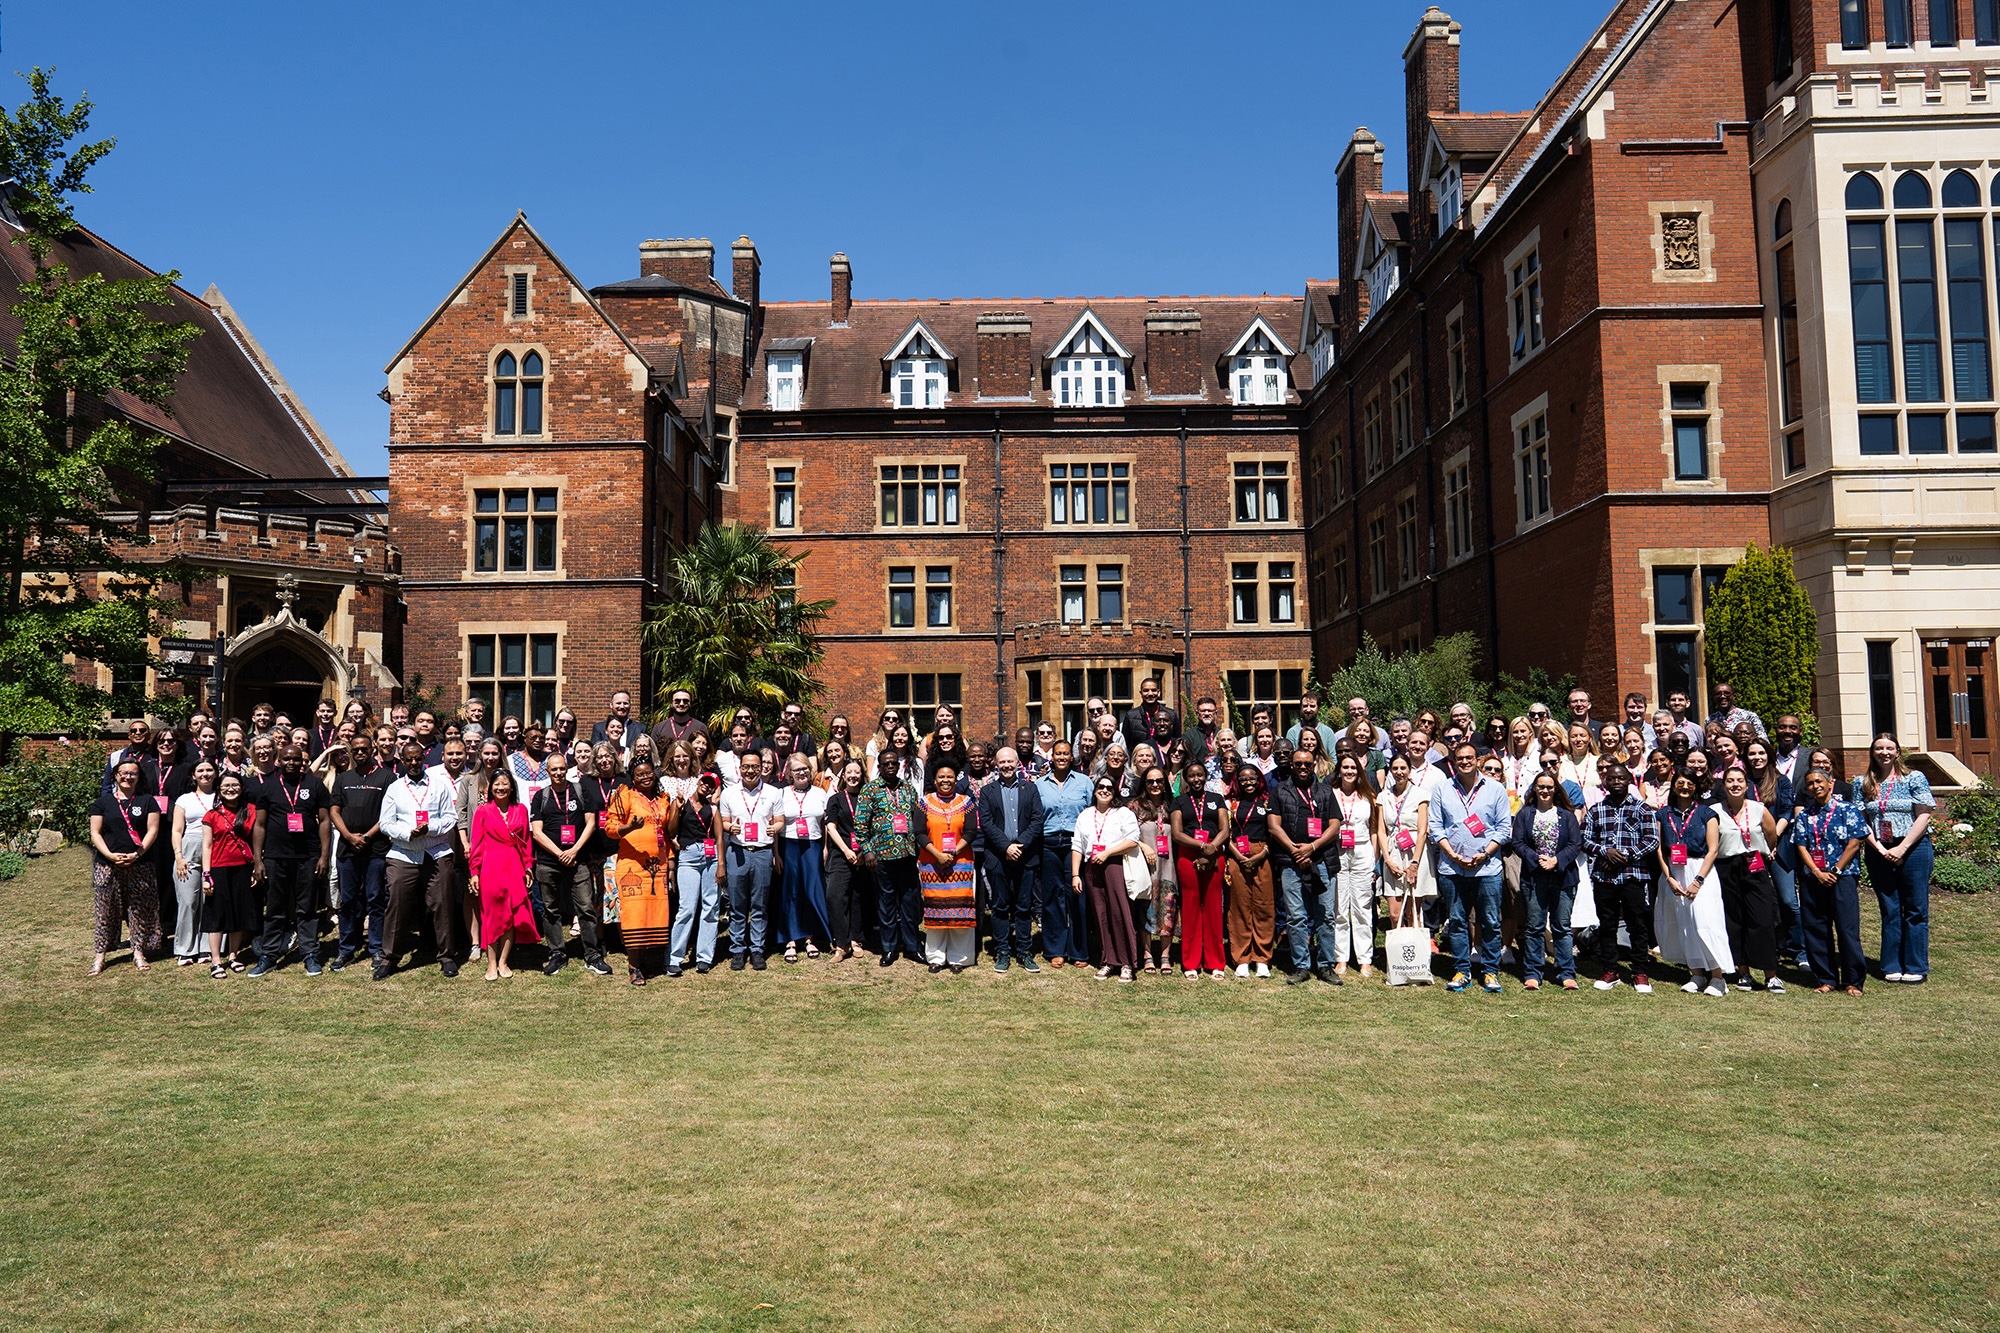
Representatives from Dojos around the world took part in our global partners summit Raspberry Fields earlier this month
Earlier this month we held Raspberry Fields, our first global partners summit in Cambridge. It was great to have representatives from Dojos around the world join in important conversations about the future of computing education and the impact of AI. Undoubtedly schools play a significant role in preparing young people for the future, but not every child thrives at or even attends school. Every conversation, panel discussion, and workshop at Raspberry Fields reminded me that the original CoderDojo approach — championing non-formal education and embracing fun, creativity, collaboration, and openness — is still immensely important. I’m really proud that these values remain a core part of CoderDojo and the wider Code Club movement today.
Continuing the mission
Raspberry Fields was a useful reminder that even in the age of AI, it’s imperative that we encourage and enable young people to learn to code. We need to help young people understand, question and shape the AI systems affecting their lives, and we need to think carefully about how we reach young people who can’t or don’t access school. We need even more clubs that will continue the mission that CoderDojo began.
The 2025 DojoCon event in the Netherlands welcomed our CEO Philip Colligan among its guests
Launching a CoderDojo is one of the most rewarding things I’ve ever done. I’m proud to be part of both CoderDojo and Code Club, and I’m proud that we continue to support all of our clubs, no matter what name they choose. If you’d like to join or launch a club in your community, head to the Code Club website to get started — I promise you won’t regret it!
Thank you to James, Bill, and everyone who has been part of the CoderDojo journey. Be cool!
PS For those of you reading this in the community in Ireland, where CoderDojo first began all those years ago, I can’t wait to hear your experiences and learn together in Athlone at Meet, Learn, Make this October.
Healthcare organizations face a critical scaling challenge – how to maintain deeply personalized patient interactions as member bases grow, without overwhelming care teams or compromising quality. At Pelago, a digital health company specializing in substance use disorder support, the engineering team found a way to build an AI-powered solution to address this challenge using AWS services in just two weeks.
In this post, you will learn how Pelago used AWS serverless and AI services, such as Amazon Bedrock and AWS Lambda, to build and deploy an event-driven AI assistant. The result is a service that generates contextually aware suggested considerations for the care team. This system preserves the human-in-the-loop oversight that healthcare demands while removing months of traditional development work and overhead of managing complex infrastructure.
The challenge overview
Pelago is a digital clinic for substance use treatment that provides comprehensive support including 1:1 coaching, medication management, and behavioral therapy. It serves members across the US to support recovery journeys for alcohol, tobacco, stimulants, cannabis, and opioid use disorder, and adjacent behaviors often associated with substance use. The Pelago care team coaches members through substance use recovery. A single coach may hold active conversations with dozens of members at once. Each message a coach sends needs to reflect weeks of prior context and drafting that response manually from scratch takes time the care team doesn’t always have.
When the Pelago engineering team set out to build an AI assistant for the care team, they faced a set of interconnected constraints. Behavioral health conversations build over weeks and months. Coaches need to account for that history in every reply. An AI assistant that only understands the most recent messages isn’t useful here – it must grasp the full long-term conversation history. That depth of context is also why human oversight is non-negotiable. The system had to generate suggestions for Pelago’s care team, not automated responses. Every piece of feedback must be read, evaluated, and adapted by a human coach before it reaches a member.
Protected Health Information (PHI) requirements added another layer of complexity – data could not leave Pelago’s AWS environment. All AI integrations must operate entirely within existing Amazon Virtual Private Cloud (VPC) infrastructure with no exposure to the public internet.
Beyond compliance and clinical safety, there were also practical constraints. Care team members need information the moment they open a conversation but generating relevant content processing dozens, sometimes hundreds, of prior messages through a large language model. A long wait was not acceptable when coaches open dozens of conversations per shift.
The engineering team needed to deliver all this quickly with full audit trails and security controls in a highly regulated environment. They had to solve the problem of pre-generating contextual suggestions without blocking the user experience while maintaining the compliance posture.
The Pelago team separated concerns using event-driven architecture. The care team needed suggested responses instantly when accessing the system but generating them synchronously in real-time blocked the user experience for tens of seconds because of LLM processing time. By treating each incoming member message as an asynchronous event, the system can fan out processing to independent consumers without coupling them to the message delivery path. A new consumer, such as the AI assistant, can be added without affecting existing components or code. And because each processing step runs in its own Lambda function, a spike in inference requests doesn’t affect message delivery or processing.
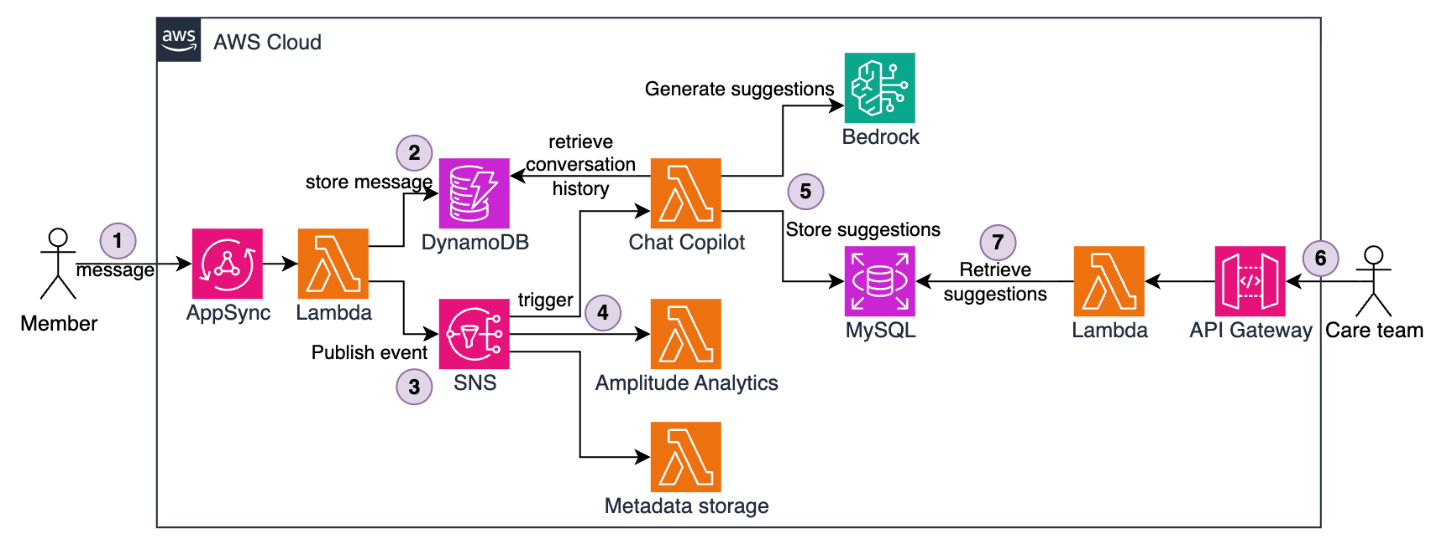
Figure 1 — The full end-to-end solution architecture
Members send messages through AWS AppSync, forwarded to a Lambda function.
The Lambda function stores messages in an Amazon DynamoDB table.
The Lambda function publishes messages to an SNS topic.
SNS fans out messages to multiple Lambda subscriber functions, such as Metadata storage, Amplitude analytics, and Chat assistant responsible for AI-based suggested message generation.
The Chat Assistant Lambda runs asynchronously. It retrieves the full conversation history from DynamoDB, invokes Amazon Bedrock to generate contextual suggestions, and stores the result in MySQL hosted on Amazon Relational Database Service (Amazon RDS). This flow happens in the background without blocking user experience and typically completing in under 10 seconds.
When a care team member opens a conversation (often minutes or hours later), the request flows through Amazon API Gateway.
A Lambda function retrieves pre-generated suggestions from MySQL.
The front end displays the suggestion in under 100 milliseconds.
This pattern keeps message delivery, analytics, and AI generation decoupled. Each member’s PHI is processed separately and stays fully within the Pelago AWS boundary. A failure or spike in feedback generation for one member does not disrupt or impact processing for other members.
Because inference happens asynchronously in the background, the care team does not wait for LLM processing. Suggested messages are pre-generated, stored, and ready to use when a coach opens a conversation. This keeps retrieval times under 100 milliseconds regardless of how long the AI generation took.
This serverless architecture also provides organic scaling. Each Lambda function automatically scales horizontally based on current traffic – scaling up during spikes and back down when demand drops, with no pre-provisioning or scaling configuration required. Adding a new event-driven downstream capability, like the AI assistant itself, requires only a new SNS subscription with no changes to existing message-publishing or handling code.
Event-driven fanout with Amazon SNS
The foundation of the Pelago chat architecture is an SNS topic that acts as a message bus for conversation events. SNS is a fully managed pub/sub messaging service. When a message is published to a topic, SNS automatically delivers it to subscribed consumers in parallel. This means a single incoming message can trigger multiple independent processing steps simultaneously.
When a user or coach sends a message, the system publishes a standardized payload to the SNS topic, for example:
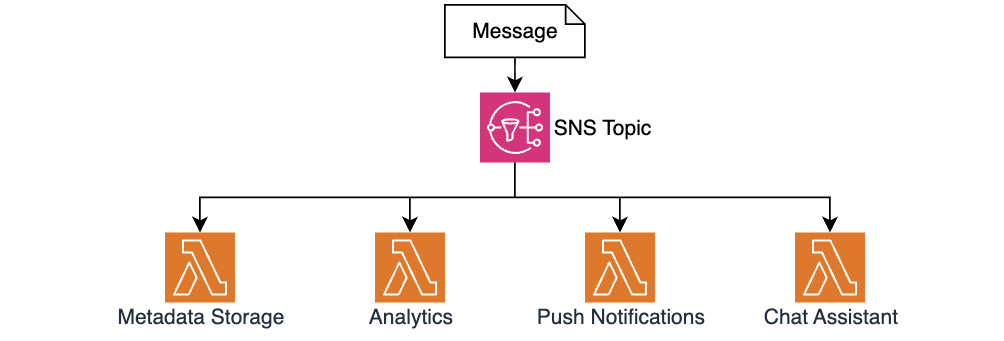
SNS delivers this event to four Lambda function subscribers. The Metadata Storage Lambda writes message metadata to MySQL for reporting. The Analytics Lambda sends events to Amplitude for product analytics. The Push Notification Lambda triggers mobile notifications for coaches. The Chat Assistant Lambda generates Assistant-based suggestions using Amazon Bedrock.
Figure 2 — Using SNS for message fan-out and decoupled processing
This fanout pattern allowed the Pelago team to add the AI Chat Assistant feature with zero changes to existing message-handling code. The team simply created a new Lambda function and added it as an SNS subscription. The publisher doesn’t need to know how many consumers exist or what they do, so new capabilities can be built and deployed independently without risking regressions in the message processing path.
Async AI generation with Amazon Bedrock
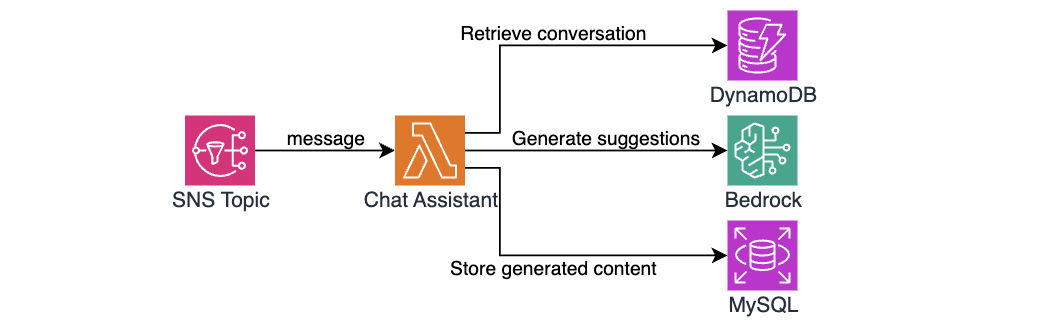
The Chat Assistant Lambda handles computationally expensive AI generation. The function implements a multi-step workflow:
Figure 3 — The chat assistant architecture and workflow
The first step is to retrieve conversation history. Behavioral health conversations can span dozens or even hundreds of messages over weeks, and the AI assistant needs all that context to generate a useful suggestion to Pelago’s care team. The function queries DynamoDB for previous messages in the conversation. The DynamoDB single-digit millisecond read performance means even lengthy conversations (50+ messages) are typically retrieved in under 20ms.
The next step is to prepare and format context for inference. The function transforms the retrieved messages structure into a conversation history format that provides Amazon Bedrock with full context, for example:
[User]: Hi, I'm struggling with cravings today

[Coach]: I hear you. Cravings can be really tough. What's happening right now that's making this moment difficult?

[User]: I'm at a party and everyone is drinking. I feel left out.

[Coach]: That's a really challenging situation, and it's completely understandable to feel that way...

[User]: I ended up leaving early. Feeling proud but also kind of sad.
After formatting the conversation, the Lambda function uses the Amazon Bedrock Runtime API to invoke Claude models. The prompt engineering focuses on empathy and validation – it helps the model acknowledge what the member is feeling rather than jumping to advice. It is tuned to maintain contextual continuity – picking up things the member mentioned in earlier messages instead of treating each exchange without prior context. It also steers the model away from false optimism or dismissive language and keeps suggestions short, more like a text message than an email. This matches how coaching conversations flow on the application.
response = bedrock_runtime.invoke_model(
    body=json.dumps({
        "anthropic_version": "bedrock-2023-05-31",
        "max_tokens": 4096,
        "temperature": 0.7,
        "system": "You are a supportive coach...",
        "messages": [{
            "role": "user",
            "content": f"""
Here is the conversation history:

<chatHistory>
{chat_history_string}
</chatHistory>

Provide the next coach message suggestion as plain text.
"""
        }]
    })
)
Measuring system performance and business impact
This entire flow, from SNS trigger to a suggestion stored in MySQL, typically completes in less than 4 seconds, well within acceptable processing time. When a care team member opens a conversation on the dashboard, the front end instantly retrieves pre-generated suggested messages. Total response time perceived by the care team is under 100 milliseconds.
The Pelago team went from technical designs to first production deployment in 2 weeks. Two days on architecture and model selection with the clinical team, three days building the core Lambdas, three days on integration testing and prompt refinement, and two final days on deployment and monitoring.
The system delivered strong early results. From the business perspective, response preparation times dropped 40% on average, and the care team rated 79.6% of AI suggestions as helpful, based on internal Pelago measurements. Operationally, using serverless services introduced no new overhead. There was no new infrastructure to manage, servers to patch, or scaling configurations to maintain. The architecture successfully handled an 8x message volume spike during a seasonal campaign without configuration changes.
Implementation details and key decisions
With the core event-driven architecture in place, the Pelago team made several implementation choices to satisfy healthcare industry requirements, handle traffic patterns unique to the application, and maintain reliability across the system.
PHI must stay secured
Pelago uses multiple AWS security features to maintain HIPAA eligibility while using AI models. One requirement is for PHI to never traverse the public internet. To address this, the Pelago team uses VPC endpoints for Amazon Bedrock, so model invocations stay within the private network. The Boto3 client in the Python Lambda automatically routes traffic through the private endpoint. Data is encrypted at rest on DynamoDB and RDS, service communications use TLS 1.2+, and IAM policies are scoped with least-privilege permissions to specific resource actions and ARNs. Audit logs of model invocations are emitted to Amazon CloudWatch and capture message IDs only, not content.
Polyglot cross-runtime implementation
The team used Python for Lambda functions that invoke Amazon Bedrock models. Boto3 native Amazon Bedrock support and simpler string manipulation made Python the right choice for building and iterating on prompts. The retrieval function is written in TypeScript to stay consistent with most of the Pelago backend code and to reuse shared libraries and Zod schemas for type-safe API contracts. This split let the team use the best language for each job without forcing a single runtime across the entire system.
Spiky traffic and pay-per-invocation compute
The Pelago application serves heavily US-based traffic. Message volume concentrates during weekday working hours, with peak hours seeing 10x or more the volume of quiet periods. The pay-per-invocation model of Lambda fits this well. During a Monday morning surge, Lambda scales out automatically with no pre-provisioning required. During off-peak hours, Lambda functions automatically scale down, so Pelago avoids idle compute costs. Using alternative long-lived compute would mean either over-provisioning for peak load or maintaining auto scaling policies that can lag during sudden spikes. With Lambda, the solution costs are directly proportional to member engagement with no idle cost.
Picking the right storage and handling idempotency
The team chose to use DynamoDB for conversation messages and MySQL for assistant suggestions based on different access patterns of each scenario. Conversation messages require high write throughput (100+ writes/sec at peak), single-digit millisecond reads, and automatic scaling. These requirements made DynamoDB a good fit. Assistant suggestions have a lighter write load (10-20 writes/sec) but need structured queries, foreign key relationships, and nested analytics joins that a relational database supports naturally.
Because SNS can deliver messages more than once, the Chat Assistant Lambda checks MySQL for an existing message before generating a new one. This idempotency check helps prevent duplicate Amazon Bedrock invocations, which would waste compute and could surface conflicting suggestions to coaches. If an Amazon Bedrock invocation fails because of throttling or model unavailability, the function logs the error without blocking message flow. A built-in retry mechanism handles transient failures, so suggestions are eventually generated even when Amazon Bedrock experiences momentary capacity constraints.
Monitoring and observability
The team tracks multiple business and operational metrics. CloudWatch metrics capture suggestion generation latency, which helps the team identify when model response times exceed acceptable thresholds. Retrieval rate measures what percentage of generated message suggestions are used by coaches. This gives insights into how well the async timing aligns with real usage patterns. The system also allows coaches to rate each suggestion with thumbs up or down. These ratings are stored in MySQL for future prompt tuning and model evaluation. CloudWatch alarms monitor error rates for Amazon Bedrock throttling and database connection failures. These alarms alert the engineering team before operational issues impact the care team experience.
Conclusion
Managed AI services like Amazon Bedrock and serverless architectures let healthcare organizations move quickly while maintaining compliance controls. The Pelago chat assistant shows what’s possible when you combine serverless event-driven processing with async AI generation and fast synchronous retrieval. The key patterns that made this work are SNS fanout to decouple processing and make new features straightforward to add, pre-generating message suggestions asynchronously so the care team does not wait, VPC endpoints to keep PHI off the public internet, and starting with foundation models and prompt engineering instead of spending months on custom model training.
The Pelago journey from concept to production deployment shows how small engineering teams in regulated industries can balance moving fast and maintaining their compliance posture.
One of the features that users often miss when moving from X11 to Wayland is
the ability to save and restore the position of windows between sessions. At GUADEC 2026, held in
A Coruña, Spain, Adrian Vovk provided an overview of work that has gone
into providing a platform-wide save and restore framework for GNOME. After two
failed attempts at landing an API, he believes that the third try will be the
one to succeed—though not in time for the upcoming GNOME 51 release
due in October.
Python Software Foundation security developer-in-residence Seth
Larson has announced
that the Python Package Index (PyPI) will now reject new files that
are uploaded to releases older than 14 days. The restriction is to
prevent the poisoning of old releases if publishing tokens or
workflows of PyPI projects are compromised.
Originally the discussion stalled due to some projects depending on this behavior
to add support for new Python versions to already-published releases. To quantify how
disruptive this change would be to existing workflows, the PyPI database was queried
for projects
that have published new files to old releases (bucketed by number of days since
the release). Later, specifically cp314 wheels were queried for the top
15,000 packages, revealing that only
56 projects of 15,000 had published a 3.14-compatible wheel more than 14 days
after a release was available.
You’ve done the storage evaluation. The per-terabyte price is right. The durability numbers check out. Compliance boxes are ticked. And still, the cloud migration project hasn’t been approved.
That’s not a coincidence.
The cloud storage industry has spent years competing on what happens after you’re already locked in: performance, redundancy, features. Almost nobody competes on what it costs to get there—or what it costs to leave.
Migration friction isn’t an oversight. For most hyperscalers, it’s a business model.
Why cloud migration projects stall before they start
The business case for cloud storage usually looks solid on paper. Lower per-terabyte costs. Less hardware to maintain. A path off aging tape libraries and overloaded NAS environments.
Then someone runs the actual migration math.
Egress fees from the current provider. Data transfer charges. Migration software licenses. Professional services. Tape digitization. Internal engineering hours. Project coordination overhead. For a large dataset, those costs can erase years of projected storage savings before a single byte moves.
Teams spend months building an approval-ready business case, only to find the upfront migration cost makes the model unworkable. The project stalls. Infrastructure the organization already knows is unsustainable stays in place. Modernization gets pushed to next quarter.
This is where most cloud vendors win. The storage decision becomes moot if the organization can never afford to move.
How egress fees trap organizations with their current provider
By the time most IT teams discover what cloud egress fees actually cost, they’re already mid-negotiation with a new provider.
The pricing model is deliberately asymmetric: getting data in is cheap, often free. Moving it out is where providers charge—and for multi-petabyte environments, those charges can run to hundreds of thousands of dollars before a migration has even started. Technically, the organization owns its data. Financially, moving it is a different question.
This reframes the evaluation in a way that favors incumbents. The question stops being which platform best fits long-term needs and becomes whether the organization can afford to leave at all. Once you’re in a major cloud platform with a large archive, exit costs are a structural retention mechanism.
Ask any prospective provider, early: what does it cost to leave? If they’re vague, that’s the answer.
How long does a cloud data migration actually take?
Cost gets scrutinized. Time usually doesn’t—until a migration is already underway and slipping.
A large-scale migration means inventorying data and metadata, evaluating and procuring tooling, coordinating across vendors, monitoring transfer jobs, validating integrity at the destination, and troubleshooting the inevitable edge cases. For multi-petabyte environments, self-managed projects routinely stretch from months into years.
Every quarter that drags on is a quarter the organization is paying to maintain infrastructure it’s already committed to replacing, while its engineering team runs a file-moving operation instead of working on anything strategic. The total cost of a slow migration almost always exceeds the initial estimate—and almost nobody builds that into the business case upfront.
What actually goes wrong during cloud data migration
Migration risk tends to be underestimated until something breaks.
The core questions—will files transfer without corruption, will metadata survive intact, will dependent applications keep working—are harder to answer than they look for LTO tape archives that haven’t been accessed in years, NAS and SAN environments with proprietary metadata structures, media archives with irreplaceable assets, regulated content with chain-of-custody requirements, and datasets large enough that verification at scale is its own engineering problem.
The cost of getting this wrong isn’t just the migration itself. Data loss, integrity gaps, or application failures discovered post-migration can be significantly more expensive than any egress fee. Validation and verification need to be designed into the plan before transfers start, not bolted on after something fails.
Why most cloud providers leave migration to you
Infrastructure teams evaluating cloud storage aren’t looking for a transfer tool. They want infrastructure modernized without burning their engineering team on a multi-year internal project. Predictable costs. A path to cloud that doesn’t require standing up a program management office just to move data.
The standard provider response is documentation and an onboarding checklist. After that, you’re largely on your own.
This isn’t an accident. Selling storage is straightforward. Owning migration means taking on cost, risk, and operational complexity that most providers would rather leave with the customer. The economics of the business favor making entry easy and exit expensive, with as little friction to growth as possible in between.
Providers that treat migration as their problem to solve are a different category. They’re betting that making it genuinely easier to get to their platform is worth more than one-time migration revenue—because a customer who gets there successfully tends to stay.
How Backblaze Universal Data Migration works
We built Universal Data Migration because we kept seeing the same thing: organizations that had already decided to move to Backblaze B2 getting stuck on the migration itself. The technology decision was made. The budget was approved. The project just couldn’t get started.
The program moves data from virtually any source—AWS S3, Microsoft Azure Blob, Google Cloud Storage, Wasabi, NAS and SAN, file servers, LTO tape across all generations, physical hard drives, legacy archives—with Backblaze managing the process rather than handing the customer a tool and a runbook.
The migration cost doesn’t have to be a reason the project stalls. That’s the point.
Before you sign a cloud storage contract, ask these two questions
The storage evaluation isn’t complete until you know what it costs to get there and what it costs to leave.
Most providers make the second number hard to find. If you have to dig for egress pricing, or if a sales rep answers the exit question with “we’d work with you on that,” build the worst-case number into your model before signing anything.
The right provider won’t make you ask. They’ll make migration part of the conversation from the start—because they’re confident enough in their platform to compete on the full picture, not just the monthly storage line.
Have a migration project that keeps getting pushed?Talk to our team about what it would actually take to move your environment to B2.
Tracepoints in the kernel are useful for a variety of purposes: debugging,
active monitoring, and performance measurements, among other things. Previously,
any given BPF program could only be attached to a single tracepoint.
Jiri Olsa has been working to change that, and led a discussion about
his progress at the 2026
Linux Storage, Filesystem, Memory-Management, and BPF
Summit. That work has since been
merged, and can be expected as part of the 7.2
kernel.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.