Сънуват ли джихадистите девици? (продължение)

Post Syndicated from Атанас Шиников original https://www.toest.bg/sanuvat-li-dzhihadistite-devici-2/

<< Към първа част

Да се върнем към заглавието на този текст и да си зададем въпроса какво ли сънуват джихадистите на съвремието.

Сънуват ли джихадистите девици? (продължение)

Ясно е, че имат всички религиозни основания да сънуват. И да употребяват сънуваното инструментално. Но какво ли сънуват? Девици, може би онези от Корана,

съпруги хубавици с големи очи (52:20),

недокоснати нито от човек преди тях, нито от джин (55:56),

с напъпили гърди девствени връстнички (78:33)?

Оказва се, че архизлодеят на терористичните атентати от 11 септември 2001 г. –

Осама бен Ладен – също е активно сънуващ.

В периода 2015–2017 г. Дирекцията за национално разузнаване (ODNI, Office of the Director of National Intelligence) на САЩ и ЦРУ постепенно публикуват серия от документи, открити в убежището на Бен Ладен в Аботабад, Пакистан, към момента на неговото ликвидиране през 2011 г. И там, наред с всички останали четива (а той, оказва се, чете и пише всякакви неща), е запазен и личният му дневник. ЦРУ се грижи за публиката си – имайте предвид, предупреждават те, че част от съдържанието може да бъде обидно или емоционално смущаващо, не е подходящо за всякаква публика и тъй като все пак е събрано от терористична организация, колкото и да се стараем да премахнем всички следи от злонамерен софтуер, това не е напълно гарантирано. 

А Бен Ладен, когото вълнуват теми като Съдния ден, края на времето, Лъжемесията в исляма (Ад-Даджжал) и „Месията“ (Ал-Махди), не сънува девици. Сънува злободневно, войнствено и политически (не напомня ли това някак на сънищата на самия Пророк и по-късните богослови, засвидетелствани например в дневника на Ибн ал-Банна?). И записва не само своите сънища, а и тези на сина си Халид:

Видях муджахидините на една страна, а на друга – настъпващите американски танкове.

Но накрая

възлязох и не намерих нито американци, нито танкове, пречист да бъдеш Ти [Аллах], слава Тебе! 

В друг сън Бен Ладен вижда Найеф бин Абдулазиз, починалия през 2012 г. престолонаследник и министър на вътрешните работи на Саудитска Арабия. В съня му обаче министърът се появява във военна униформа, но не като враг, а като приятел. Бен Ладен отбелязва и тълкуванието на съня – явно „Родът на Сауд (саудитската династия) е по-бърз от нас в приближаването си към муджахидините и благочестивата младеж“.

Свидетелства за ролята на сънищата в легитимирането на дейността на „Ал-Кайда“ съществуват и преди дневника на Бен Ладен. 

Терористичните атаки от 11 септември, оказва се, също са „предсказани“ чрез сънища на мюсюлмани. Това разкрива записът на разговор, подслушан от американското разузнаване и публикуван навремето от Министерството на отбраната на САЩ. Транскрипцията, понастоящем частично достъпна в статия на Тамара Албертини¹, отдавна вече не е налична в посочените от авторката източници онлайн. Но запазеното копие говори за т.нар. срещи от Кандахар в Афганистан. По време на събранията глас, за който се предполага, че принадлежи на Бен Ладен, наред с шейха домакин, както и други неидентифицирани персонажи споменават за общо седем видения по време на сън. Те разкриват, че на 11 септември 2001 г. ще има терористичен атентат.

Самият Бен Ладен споделя, че негов съратник (вероятно Ал-Масри, лидер на „Ал-Кайда“ от Египет) му казал преди година:

Видях в сън, че играем футбол срещу американците. Когато отборът ни се появи на игрището, всички те бяха пилоти! Тъй че се зачудих дали това е игра на футбол, или пилотска игра? Нашите играчи бяха пилоти.

А той – Абу ал-Хасан ал-Масри, – потвърждава самият Бен Ладен в записа, не знаел нищо за операцията, докато не чул за нея по радиото.

Да, Абд ар-Рахман ал-Гамри твърди, че преди операцията видял във видение насън как самолет се блъска във висока сграда, без да знае –

потвърждава непознат глас. Шейхът на свой ред казва, че различни благочестиви хора споделят с него как насън виждат, че носят огромен самолет на рамене и го влачат през пустинята, както и че хора, тръгнали на джихад, стигат до Ню Йорк и Вашингтон. В този момент самият Бен Ладен предупреждава, че започва да се безпокои да не би тайният заговор за терористичната операция да бъде разкрит, ако всички започнат да я сънуват².

Но да не си помислихте, че е само Бен Ладен? Според Иън Р. Едгар от Университета в Дърам, Великобритания³,

джихадистите, включително и отгледаните на местна почва, доста настойчиво сънуват, за да легитимират дейността си.

А на сънищата на едноокия Молла Омар, дългогодишен лидер на талибаните в Афганистан, може да се посвети отделен научен труд. Рахимуллах Юсуфзай, кореспондент на Би Би Си в Пешавар, успява да се срещне за около дванайсет интервюта с талибанския лидер и засвидетелства многократно позоваването на сънищата в „кариерата“ на Молла Омар. Ръководството му на ислямското фундаменталистко движение изглежда белязано от многобройни сънища. Чичото на жена му разказвал, че „преди да нападне дадено място, сънувал. И след това на сутринта издавал заповед на някой командир да атакува“.

Например на 20 ноември 2001 г., по време на войната в Афганистан, се оказва, че мирното предаване на Кандахар е осуетено, след като едноокият талибански водач вижда сън. Самото му възкачване на лидерската позиция е бетонирано от сънища, а съратниците му успяват да бъдат убедени, че предводителят им е човек, който се ръководи от сънища, дадени от Аллах. Подобно на съратниците на Бен Ладен, младият му брат сънува преди 11 септември, че „някъде един бял палат гори“⁴.

Нека сега да направим пълен кръг и да се върнем към началото на този текст.

Онзи ден потърсих популярни български съновници онлайн. Преживяването да ги четеш е почти като да надзърнеш в „тъмната мрежа“. Знаеш, че съществува, но предпочиташ да не го заглеждаш. Но ето, всички, на които се натъкнах, казват, че да сънуваш „ходжа“ (дано да не са тия, описвани от поп Минчо Кънчев) имало особено значение и ще се разкайваш за глупави постъпки или необмислени думи. Добре, хайде да се опитам да хакна наум сънувателната матрица. 

Ами ако самият ти насън си ходжа? 

Това значи, че някой се страхува от теб. Машаллах!, бих отвърнал аз с класическото арабско възклицание. Със сигурност това тълкувание днес при нас се е промъкнало под влиянието на мюсюлманската традиция. Няма как да сънуваш ходжа, ако не знаеш какво е. Идва от турската дума за „учител“ и се е превърнало в почетно обръщение към по-старшите, включително и към религиозните авторитети. 

А пък аз съм сънувал, че говоря на арабски в иракски казарми от времето на Саддам Хюсеин. Че карам трактор. Че съм вампир с кожени крила, кацнал на тераса в постапокалиптична тропическа панелна София. Че компаниите и екипите, които одитирам в моята работа за ИТ индустрията, се бавят и манипулират документални доказателства.

Но да сънувате ходжа? Не ми се вижда много вероятно да сънувате ходжа. На фона на всичко по-горе, е по-вероятно ходжата да сънува вас. 

1 Albertini, Tamara. “Dreams, Visions, & Nightmares: From the Prophet Muhammad to the Fundamentalist Mindset” In Dreams and Visions, ed. by Nancy van Deusen, Leiden: Brill, 2010, p. 167–182.

2 Ibid., p. 168–169.

3 Edgar, Iain R. The Dream in Islam: From Qur’anic Tradition to Jihadist Inspiration, Berghahn Books, New York, Oxford, 2016.

4 Ibid., р. 80–83.

В рубриката „Ориент кафе“ Атанас Шиников поднася любопитни теми, свързани не толкова с горещата политика, колкото с историята и културата на Близкия изток. А той, древен и днешен, е по-близко до нас и съвремието ни, отколкото си представяме.

Zabbix 7.0 Proxy Load Balancing

Post Syndicated from Markku Leiniö original https://blog.zabbix.com/zabbix-7-0-proxy-load-balancing/28173/

One of the new features in Zabbix 7.0 LTS is proxy load balancing. As the documentation says:

Proxy load balancing allows monitoring hosts by a proxy group with automated distribution of hosts between proxies and high proxy availability.

If one proxy from the proxy group goes offline, its hosts will be immediately distributed among other proxies having the least assigned hosts in the group.

Proxy group is the new construct that enables Zabbix server to make dynamic decisions about the monitoring responsibilities within the group(s) of proxies. As you can see in the documentation, the proxy group has only a minimal set of configurable settings.

One important background information to understand is that Zabbix server always knows (within reasonable timeframe) which proxies in the proxy groups are online and which are not. That’s because all active proxies connect to the Zabbix server every 1 second by default (DataSenderFrequency setting in the proxy), and Zabbix server connects to the passive proxies also every 1 second by default (ProxyDataFrequency setting in the server), so if those connections are not happening anymore, then something is wrong with using the proxy.

Initially Zabbix server will balance the hosts between the proxies in the proxy group. It can also rebalance the hosts later if needed, the algorithm is described in the documentation. That’s something we don’t need to configure (that’s the “automated distribution of hosts” mentioned above). The idea is that, at any given time, any host configured to be monitored by the proxy group is monitored by one proxy only.

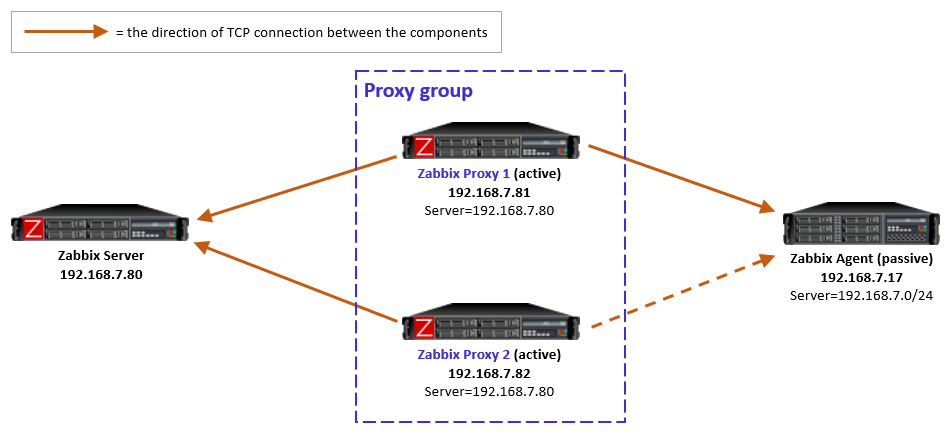
Now let’s see how the actual connections work with active and passive Zabbix agents. The active/passive modes of the proxies (with the Zabbix server connectivity) don’t matter in this context, but I’m using active proxies in my tests for simplicity.

Disclaimer: These are my own observations from my own Zabbix setup using 7.0.0, and they are not necessarily based on any official Zabbix documentation. I’m open for any comments or corrections in any case.

At the very end of this post I have included samples of captured agent traffic for each of the cases mentioned below.

Passive agents monitored by a proxy group

For passive agents the proxy load balancing really is this simple: Whenever a proxy goes down in a proxy group, all the hosts that were previously monitored by that proxy will then be monitored by the other available proxies in the same proxy group.

There is nothing new to configure in the passive agents, only the usual Server directive to allow specific proxies (IP addresses, DNS names, subnets) to communicate with the agent.

As a reminder, a passive agent means that it listens to incoming requests from Zabbix proxies (or the Zabbix server), and then collects and returns the requested data. All relevant firewalls also need to be configured to allow the connections from the Zabbix proxies to the agent TCP port 10050.

As yet another reminder, each agent (or monitored host) can have both passive and active items configured, which means that it will both listen to incoming Zabbix requests but also actively request any active tasks from Zabbix proxies or servers. But again, this is long-existing functionality, nothing new in Zabbix 7.0.

Active agents monitored by a proxy group

For active agents the proxy load balancing needs a bit new tweaking in the agent side.

By definition, an active agent is the party that initiates the connection to the Zabbix proxy (or server), to TCP port 10051 by default. The configuration happens with the ServerActive directive in the agent configuration. According to the official documentation, providing multiple comma-separated addresses in the ServerActive directive has been possible for ages, but it is for the purpose of providing data to multiple independent Zabbix installations at the same time. (Think about a Zabbix agent on a monitored host, being monitored by both a service provider and the inhouse IT department.)

Using semicolon-separated server addresses in ServerActive directive has been possible since Zabbix 6.0 when Zabbix servers are configured in high-availability cluster. That requires specific Zabbix server database implementation so that all the cluster nodes use the same database, and some other shared configurations.

Now in Zabbix 7.0 this same configuration style can be used for the agent to connect to all proxies in the proxy group, by entering all the proxy addresses in the ServerActive configuration, semicolon-separated. However, to be exact, this is not described in the ServerActive documentation as of this writing. Rather, it specifically says “More than one Zabbix proxy should not be specified from each Zabbix server/cluster.” But it works, let’s see how.

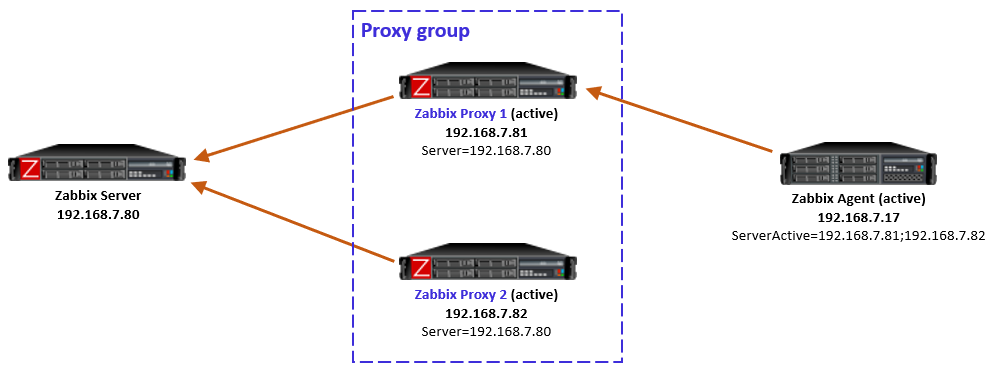
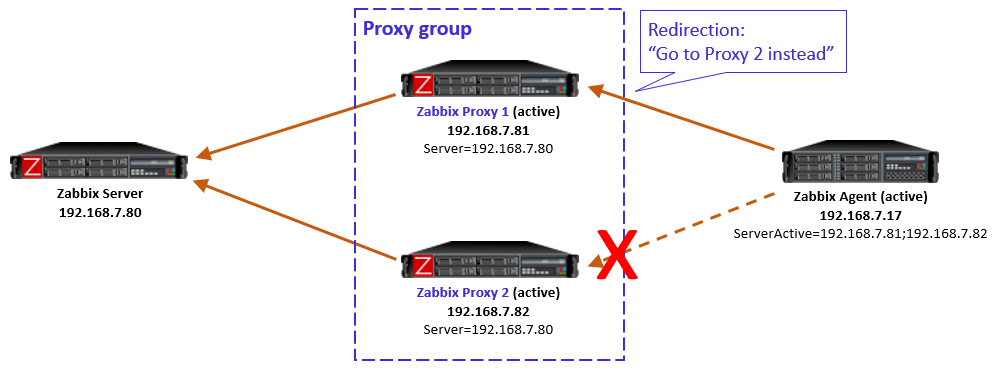
Using multiple semicolon-separated proxy addresses works because of the new redirection functionality in the proxy-agent communication: Whenever an active agent sends a message to a proxy, the proxy tells the agent to connect to another proxy, if the agent is currently assigned to some other proxy. The agent then ceases connecting to that previous proxy, and starts using the proxy address provided in the redirection instead. Thus the agent converges to using only that one designated proxy address.

In this simple example the Zabbix server determined that the agent should be monitored by Proxy 1, so when the agent initially contacted Proxy 1 (because its IP address is first in the ServerActive list), the proxy responded normally and agent was happy with that.

In case the Zabbix server had for any reason determined that the agent should be monitored by Proxy 2, then Proxy 1 would have responded with a redirection, and agent would have followed that. (There will be examples of redirections in the capture files below.)

To be clear, this agent redirection from the proxy group works only with Zabbix 7.0 agents as of this writing.

Note: In the initial version of this post I used comma-separated proxy addresses in ServerActive (instead of semicolon-separated), and that caused duplicate connections from the agent to the designated proxy (because the agent is not equipped to recognize that it connects to the same proxy twice), eventually causing data duplication in Zabbix database. Using comma-separated proxy addresses is thus not a working solution for proxy load balancing usage.

If the host-proxy assignments are changed by the Zabbix server for balancing the load between the proxies, the previously designated proxy will redirect the agent to the correct proxy address, and the situation is optimized again.

Side note: When configuring the proxies in Zabbix UI, there is a new Address for active agents field. That is the address value that is used by the proxies when responding with redirection messages to agents.

Proxy group failure scenarios with active agents

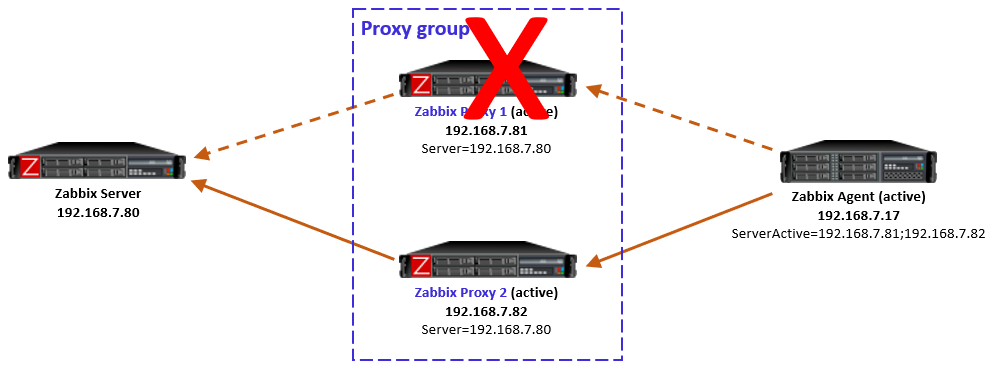
Proxy goes down

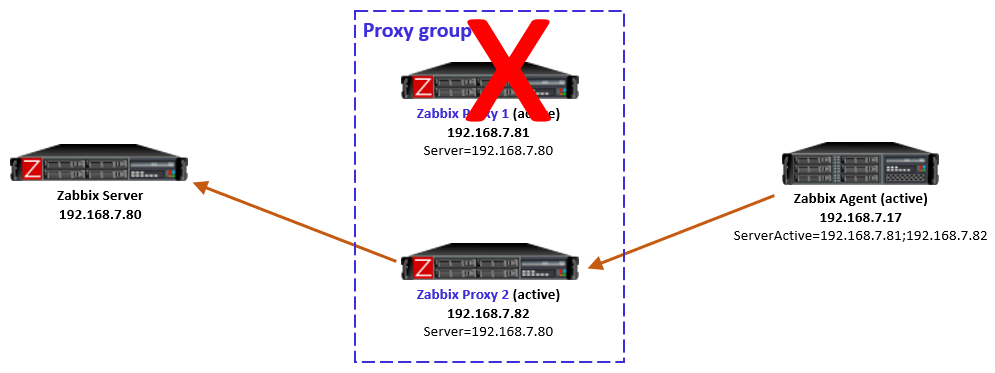
If the designated proxy of an active agent goes offline so that it doesn’t respond to the agent anymore, agent realizes the situation, discards the redirection information it had, and reverts to using the proxy addresses from ServerActive directive again.

Now, this is an interesting case because of some timing dependencies. In the proxy group configuration there is the Failover period configuration that controls the Zabbix server’s sensitivity to proxy availability in regards to agent rebalancing within the proxy group. Thus, if the agent reverts to using the other proxies faster than Zabbix server recognizes the situation and notifies the other proxies in the proxy group, the agent will get redirection responses from the other proxies, telling it to use the currently offline proxy. And the same happens again: agent fails to connect to the redirected proxy, and reverts to using the other locally configured proxies, and so on.

In my tests this looping was not very intense, only two rounds every second, so it was not very significant network-wise, and the situation will converge automatically when the Zabbix server has notified the proxies about the host rebalancing.

So this temporary looping is not a big deal. The takeaway is that the whole system converges automatically from a failed proxy.

After the failed proxy has recovered to online mode, the agents stay with their designated proxies in the proxy group.

As mentioned in the beginning, Zabbix server will automatically rebalance the hosts again after some time if needed.

Proxy is online but unreachable from the active agent

Another interesting case is one where the proxy itself is running and communicating with Zabbix server, thus being in online mode in the proxy group, but the active agent is not able to reach it, while still being able to connect to the other proxies in the group. This can happen due to various Internet-related routing issues for example, if the proxies are geographically distributed and far away from the agent.

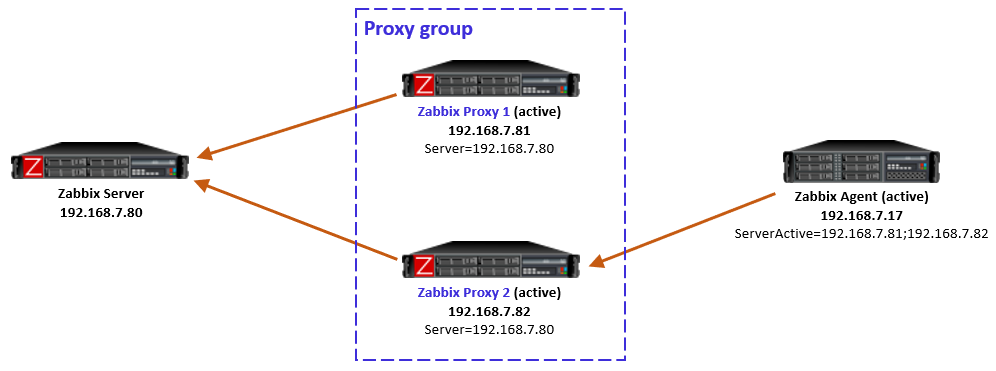
Let’s start with the situation where the agent is currently monitored by Proxy 2 (as per the last picture above). When the failure starts and agent realizes that the connections to Proxy 2 are not succeeding anymore, the agent reverts to using the configured proxies in ServerActive, connecting to Proxy 1.

But, Proxy 1 knows (by the information given by Zabbix server) that Proxy 2 is still online and that the agent should be monitored by Proxy 2, so Proxy 1 responds to the agent with a redirection.

Obviously that won’t work for the agent as it doesn’t have connectivity to Proxy 2 anymore.

This is a non-recoverable situation (at least with the current Zabbix 7.0.0) while the reachability issue persists: The agent keeps on contacting Proxy 1, keeps receiving the redirection, and the same repeats over and over again.

Note that it does not matter if the agent is now locally reconfigured to only use Proxy 1 in this situation, because the load balancing of the hosts in the proxy group is not controlled by any of the agent-local configuration. The proxy group (led by Zabbix server) has the only authority to assign the hosts to the proxies.

One way to escape from this situation is to stop the unreachable Proxy 2. That way the Zabbix server will eventually notice that Proxy 2 is offline, and the hosts will be automatically rebalanced to other proxies in the group, thus removing the agent-side redirection to the unreachable proxy.

Keep this potential scenario in mind when planning proxy groups with proxy location diversity.

This is also something to think about if your Zabbix proxies have multiple network interfaces, where Zabbix server connectivity is using different interface from the agent connectivity. In that case the same problem can occur due to your own configurations.

Closing words

All in all, proxy load balancing looks very promising feature as it does not require any network-level tricks to achieve load balancing and high availability. In Zabbix 7.0 this is a new feature, so we can expect some further development for the details and behavior in the upcoming releases.


Appendix: Sample capture files

Ideally these capture files should be viewed with Wireshark version 4.3.0rc1 or newer because only the latest Wireshark builds include support for latest Zabbix protocol features. Wireshark 4.2.x should also show most of the Zabbix packet fields. Use display filter “zabbix” to see only the Zabbix protocol packets, but when examining cases more carefully you should also check the plain TCP packets (without any display filter) to get more understanding about the cases.

These samples are taken with Zabbix components version 7.0.0, using default timers in the Zabbix process configurations, and 20 seconds as the proxy group failover period.

Passive agent, with proxy failover

    • After frame #50 Proxy 1 was stopped and Proxy 2 eventually took over the monitoring

Active agent, with proxy failover

    • The agent initially communicates with Proxy 1
    • Proxy 1 was stopped before frame #425
    • Agent connected to Proxy 2, but Proxy 2 keeps sending redirects
    • Proxy 2 was assigned the agent before frame #1074, so it took over the monitoring and accepted the agent connections
    • Proxy 1 was later restarted (but agent didn’t try to connect to it yet)
    • The agent was manually restarted before frame #1498 and it connected to Proxy 1 again, was given a redirection to Proxy 2, and continued with Proxy 2 again

Active agent, with proxy unreachable

    • Started with Proxy 2 monitoring the agent normally
    • Network started dropping all packets from the agent to Proxy 2 before frame #179, agent started connecting to Proxy 1 almost immediately
    • From frame #181 on Proxy 1 responds with redirection to Proxy 2 (which is not working)
    • Proxy 2 was eventually stopped manually
    • Redirections continue until frame #781 when Proxy 1 is assigned the monitoring of the agent, and Proxy 1 starts accepting the agent requests

This post was originally published on the author’s blog.

The post Zabbix 7.0 Proxy Load Balancing appeared first on Zabbix Blog.

AI and the Indian Election

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/ai-and-the-indian-election.html

As India concluded the world’s largest election on June 5, 2024, with over 640 million votes counted, observers could assess how the various parties and factions used artificial intelligence technologies—and what lessons that holds for the rest of the world.

The campaigns made extensive use of AI, including deepfake impersonations of candidates, celebrities and dead politicians. By some estimates, millions of Indian voters viewed deepfakes.

But, despite fears of widespread disinformation, for the most part the campaigns, candidates and activists used AI constructively in the election. They used AI for typical political activities, including mudslinging, but primarily to better connect with voters.

Deepfakes without the deception

Political parties in India spent an estimated US$50 million on authorized AI-generated content for targeted communication with their constituencies this election cycle. And it was largely successful.

Indian political strategists have long recognized the influence of personality and emotion on their constituents, and they started using AI to bolster their messaging. Young and upcoming AI companies like The Indian Deepfaker, which started out serving the entertainment industry, quickly responded to this growing demand for AI-generated campaign material.

In January, Muthuvel Karunanidhi, former chief minister of the southern state of Tamil Nadu for two decades, appeared via video at his party’s youth wing conference. He wore his signature yellow scarf, white shirt, dark glasses and had his familiar stance—head slightly bent sideways. But Karunanidhi died in 2018. His party authorized the deepfake.

In February, the All-India Anna Dravidian Progressive Federation party’s official X account posted an audio clip of Jayaram Jayalalithaa, the iconic superstar of Tamil politics colloquially called “Amma” or “Mother.” Jayalalithaa died in 2016.

Meanwhile, voters received calls from their local representatives to discuss local issues—except the leader on the other end of the phone was an AI impersonation. Bhartiya Janta Party (BJP) workers like Shakti Singh Rathore have been frequenting AI startups to send personalized videos to specific voters about the government benefits they received and asking for their vote over WhatsApp.

Multilingual boost

Deepfakes were not the only manifestation of AI in the Indian elections. Long before the election began, Indian Prime Minister Narendra Modi addressed a tightly packed crowd celebrating links between the state of Tamil Nadu in the south of India and the city of Varanasi in the northern state of Uttar Pradesh. Instructing his audience to put on earphones, Modi proudly announced the launch of his “new AI technology” as his Hindi speech was translated to Tamil in real time.

In a country with 22 official languages and almost 780 unofficial recorded languages, the BJP adopted AI tools to make Modi’s personality accessible to voters in regions where Hindi is not easily understood. Since 2022, Modi and his BJP have been using the AI-powered tool Bhashini, embedded in the NaMo mobile app, to translate Modi’s speeches with voiceovers in Telugu, Tamil, Malayalam, Kannada, Odia, Bengali, Marathi and Punjabi.

As part of their demos, some AI companies circulated their own viral versions of Modi’s famous monthly radio show “Mann Ki Baat,” which loosely translates to “From the Heart,” which they voice cloned to regional languages.

Adversarial uses

Indian political parties doubled down on online trolling, using AI to augment their ongoing meme wars. Early in the election season, the Indian National Congress released a short clip to its 6 million followers on Instagram, taking the title track from a new Hindi music album named “Chor” (thief). The video grafted Modi’s digital likeness onto the lead singer and cloned his voice with reworked lyrics critiquing his close ties to Indian business tycoons.

The BJP retaliated with its own video, on its 7-million-follower Instagram account, featuring a supercut of Modi campaigning on the streets, mixed with clips of his supporters but set to unique music. It was an old patriotic Hindi song sung by famous singer Mahendra Kapoor, who passed away in 2008 but was resurrected with AI voice cloning.

Modi himself quote-tweeted an AI-created video of him dancing—a common meme that alters footage of rapper Lil Yachty on stage—commenting “such creativity in peak poll season is truly a delight.”

In some cases, the violent rhetoric in Modi’s campaign that put Muslims at risk and incited violence was conveyed using generative AI tools, but the harm can be traced back to the hateful rhetoric itself and not necessarily the AI tools used to spread it.

The Indian experience

India is an early adopter, and the country’s experiments with AI serve as an illustration of what the rest of the world can expect in future elections. The technology’s ability to produce nonconsensual deepfakes of anyone can make it harder to tell truth from fiction, but its consensual uses are likely to make democracy more accessible.

The Indian election’s embrace of AI that began with entertainment, political meme wars, emotional appeals to people, resurrected politicians and persuasion through personalized phone calls to voters has opened a pathway for the role of AI in participatory democracy.

The surprise outcome of the election, with the BJP’s failure to win its predicted parliamentary majority, and India’s return to a deeply competitive political system especially highlights the possibility for AI to have a positive role in deliberative democracy and representative governance.

Lessons for the world’s democracies

It’s a goal of any political party or candidate in a democracy to have more targeted touch points with their constituents. The Indian elections have shown a unique attempt at using AI for more individualized communication across linguistically and ethnically diverse constituencies, and making their messages more accessible, especially to rural, low-income populations.

AI and the future of participatory democracy could make constituent communication not just personalized but also a dialogue, so voters can share their demands and experiences directly with their representatives—at speed and scale.

India can be an example of taking its recent fluency in AI-assisted party-to-people communications and moving it beyond politics. The government is already using these platforms to provide government services to citizens in their native languages.

If used safely and ethically, this technology could be an opportunity for a new era in representative governance, especially for the needs and experiences of people in rural areas to reach Parliament.

This essay was written with Vandinika Shukla and previously appeared in The Conversation.

Accelerate your Automation for SAP on AWS Operations using Amazon Q Developer

Post Syndicated from Bidwan Baruah original https://aws.amazon.com/blogs/devops/accelerate-your-automation-for-sap-on-aws-operations-using-amazon-q-developer/

Based on discussions with several SAP on AWS customers, we have discovered that the number of SAP administration or operational task requirements often exceed the capacity of the available team. Due to lack of time, resources, and heavy focus on operations, strategic initiatives like digital transformations often remain unaddressed. Although 1P and 3P automation solutions are available, many organizations do not adopt them, due to cost, internal processes, complexities associated with managing multiple-vendor tooling, etc. While some SAP BASIS teams have successfully automated some tasks, the level of effort and skill set to develop custom scripts is not widely available, in some cases due to a skills gap or insufficient knowledge in scripting. In this blog post we will use Amazon Q Developer, a generative AI coding assistant, and use natural language to create SAP operational automation in a more productive fashion.

Walkthrough

Amazon Q Developer acts as a bridge between logical comprehension and practical coding implementation. It enables SAP BASIS administrators to translate their operational understanding into code by interpreting their logic, articulated in natural language. This approach allows us to accelerate the development process of automation scripts, democratizing script development to a broader base of infrastructure and application administrators. In this case, Amazon Q provides coding suggestions by converting natural English language explanations of logic into operational code, such as an automation script for the operational activity (e.g., Start and Stop of SAP).

The solution is orchestrated in two stages:

  • Administrators use Q Developer using natural language to formulate a shell script to perform start and stop operations on a single Amazon EC2 instance.
  • Q Developer validates inputs, assessment of system installation, and execution of start/stop commands.

Prerequisites

For the walkthrough, we are using VS Codium for our integrated development environment (IDE) with the latest Amazon Q Developer extension installed. However, you may use any of the supported IDEs.

Prior to starting, it may be important to model the entire workflow. For example, the script may need a number of conditions, checks, and logical considerations. However, for the purposes of our scenario, we focus on three specific conditions, checks, and logical processes. For your specific use case, we recommend incorporating additional logical steps, if needed.

The script we will write has 3 arguments in order to Start/Stop the SAP System.

  • The SAP System ID (SID)
  • The SAP Instance Number
  • The command ‘start’ or ‘stop’ – will start or stop the SAP system.

To run the script the command should look like the example below:

scriptname.sh <SID> <InstanceNumber> <start/stop>

There are also four conditions, checks, and logic blocks in the script,

  1. First, check if the command has 3 arguments.  If any are missing, the system will not be able to perform the intended action.
  2. Second, check if the SAP system (SID) we are trying to manage is available in the current EC2 instance.
  3. Third, the SAP Instance Number is checked in the current EC2 instance.
  4. Lastly, the script needs to tell the system which command to run, based on the third argument (e.g., start or stop).

Important: Comments in Shell scripts start with a ‘#’ sign, and the arguments are indicated by a ‘$<n>’ format; n being the sequence number of the argument. So, in our case:

<SID> : $1
<InstanceNumber> : $2
<start/stop> : $3

Now that we have established the structure of how to call the script and what arguments we are going to pass, lets write the comments in English to get code recommendations from Amazon Q.

Getting Started

1.     In VS Codium, create a ‘New File’ for our script. Assign a file name and make sure the file extension ends with a ‘.sh’ (e.g., startstopsap.sh).

Below is an example of the comments we used for our logic. Copy paste this into the file.

Info: The first line #!/bin/bash tells the system to execute the script using the Bash shell. The rest of the lines tell what the script needs to check, the logic it needs to follow and the commands it needs to run.

#!/bin/bash 
#This is a script that is going to start and stop an SAP instance based on the given inputs to the script
#The script will receive 3 inputs. <SID> <InstanceNumber> <start/stop>
#If the script did not get 3 inputs, the script will fail with showing the usage guidance. 
#Check if the file "/usr/sap/sapservices" exists. If not, fail.
#We will check if the given SID is installed in this server by searching the SID in the file "/usr/sap/sapservices"  If it does not exist, fail, otherwise continue. 
#Then we will check if the given instance number is installed in this server by searching the Instance Number in the file "/usr/sap/sapservices”. If it does not exist, fail, otherwise continue. 
#If all conditions met, check the third output and if it's start, start the sap system using "sapcontrol -nr InstanceNumber -function Start"
#If all conditions met, see the third output and if it's stop, stop the sap system using "sapcontrol -nr InstanceNumber -function Stop"
#Then wait for 2 minutes for the stop command to complete (if stop)
#Remove the ipcs (if stop) by the command “cleanipc InstanceNumber remove” 
#If the third input is not start or stop, fail.
#End the script.

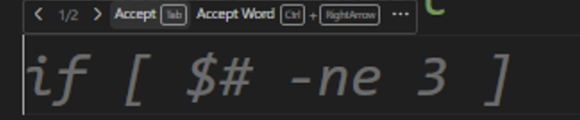
2.     Type #Check Input and press Enter, Q will start making code suggestions. If it does not, you can manually invoke suggestions with ‘Option+C’ on Mac or ‘Alt+C’ on Windows.

Figure 1 – Amazon Q Developer Suggestions

3.     To accept suggested code, either press ‘Tab’ or click on ‘Accept’.

The ‘< 1/2 >’ means that there are two suggestions and you may accept the one that is most appropriate for the scenario. Toggle between the suggestions using right and left arrows on your keyboard.

We will accept the code and then press Enter to move to the next line. As soon as you press the Enter key, the next line of code will be suggested.

Important: Amazon Q Developer is non-deterministic, which means that code suggestions produced may be different from what is shown in the blog.  If the suggestions look different for you, you can use the arrows on your keyboard to toggle between recommendations, as shown below.

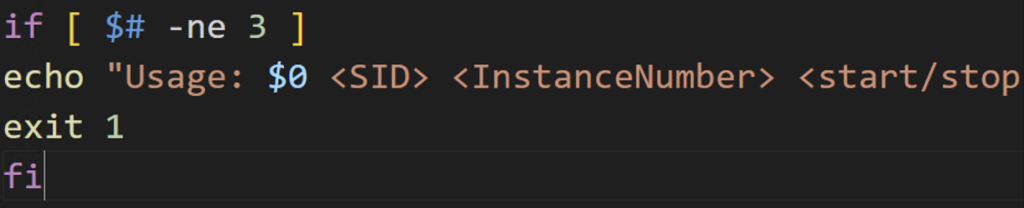
4.     Accept the next block of code and eventually close the IF loop.  Press Enter.

Figure 2 – Reviewing Suggestions

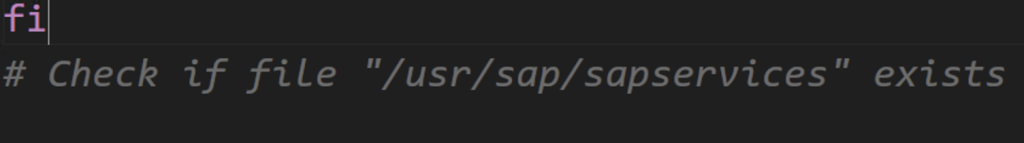
5.     Based on comments in the file, Q should should have enough context to suggest what needs to be done next. The script should check if the /usr/sap/sapservices file exists.

Figure 3 – Checking dependencies

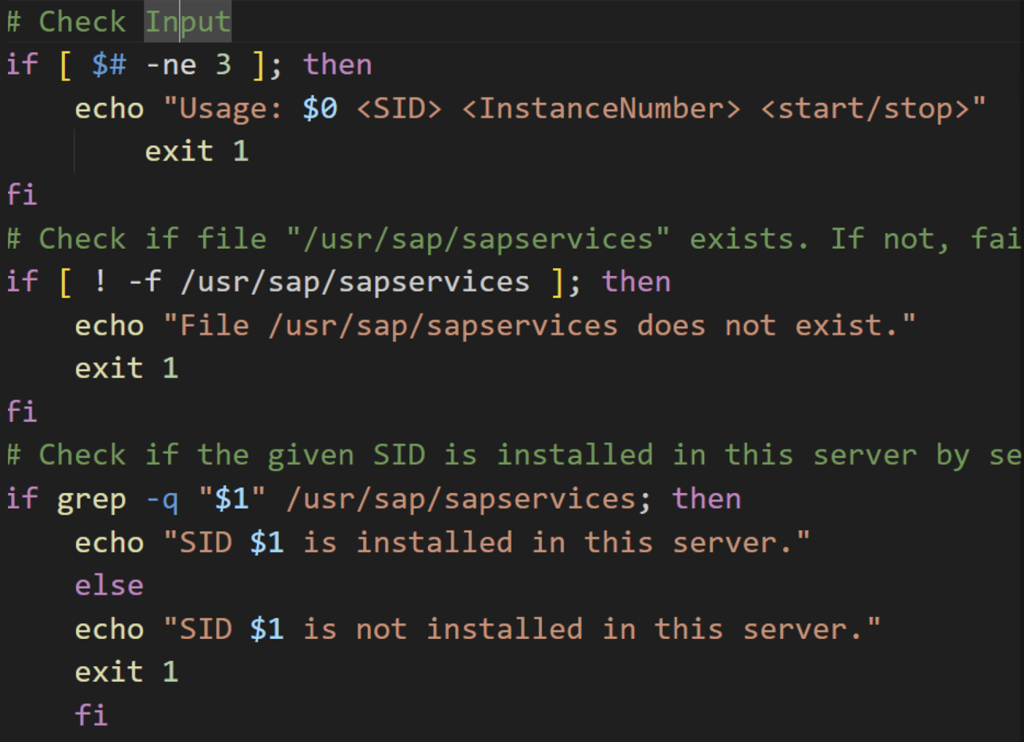
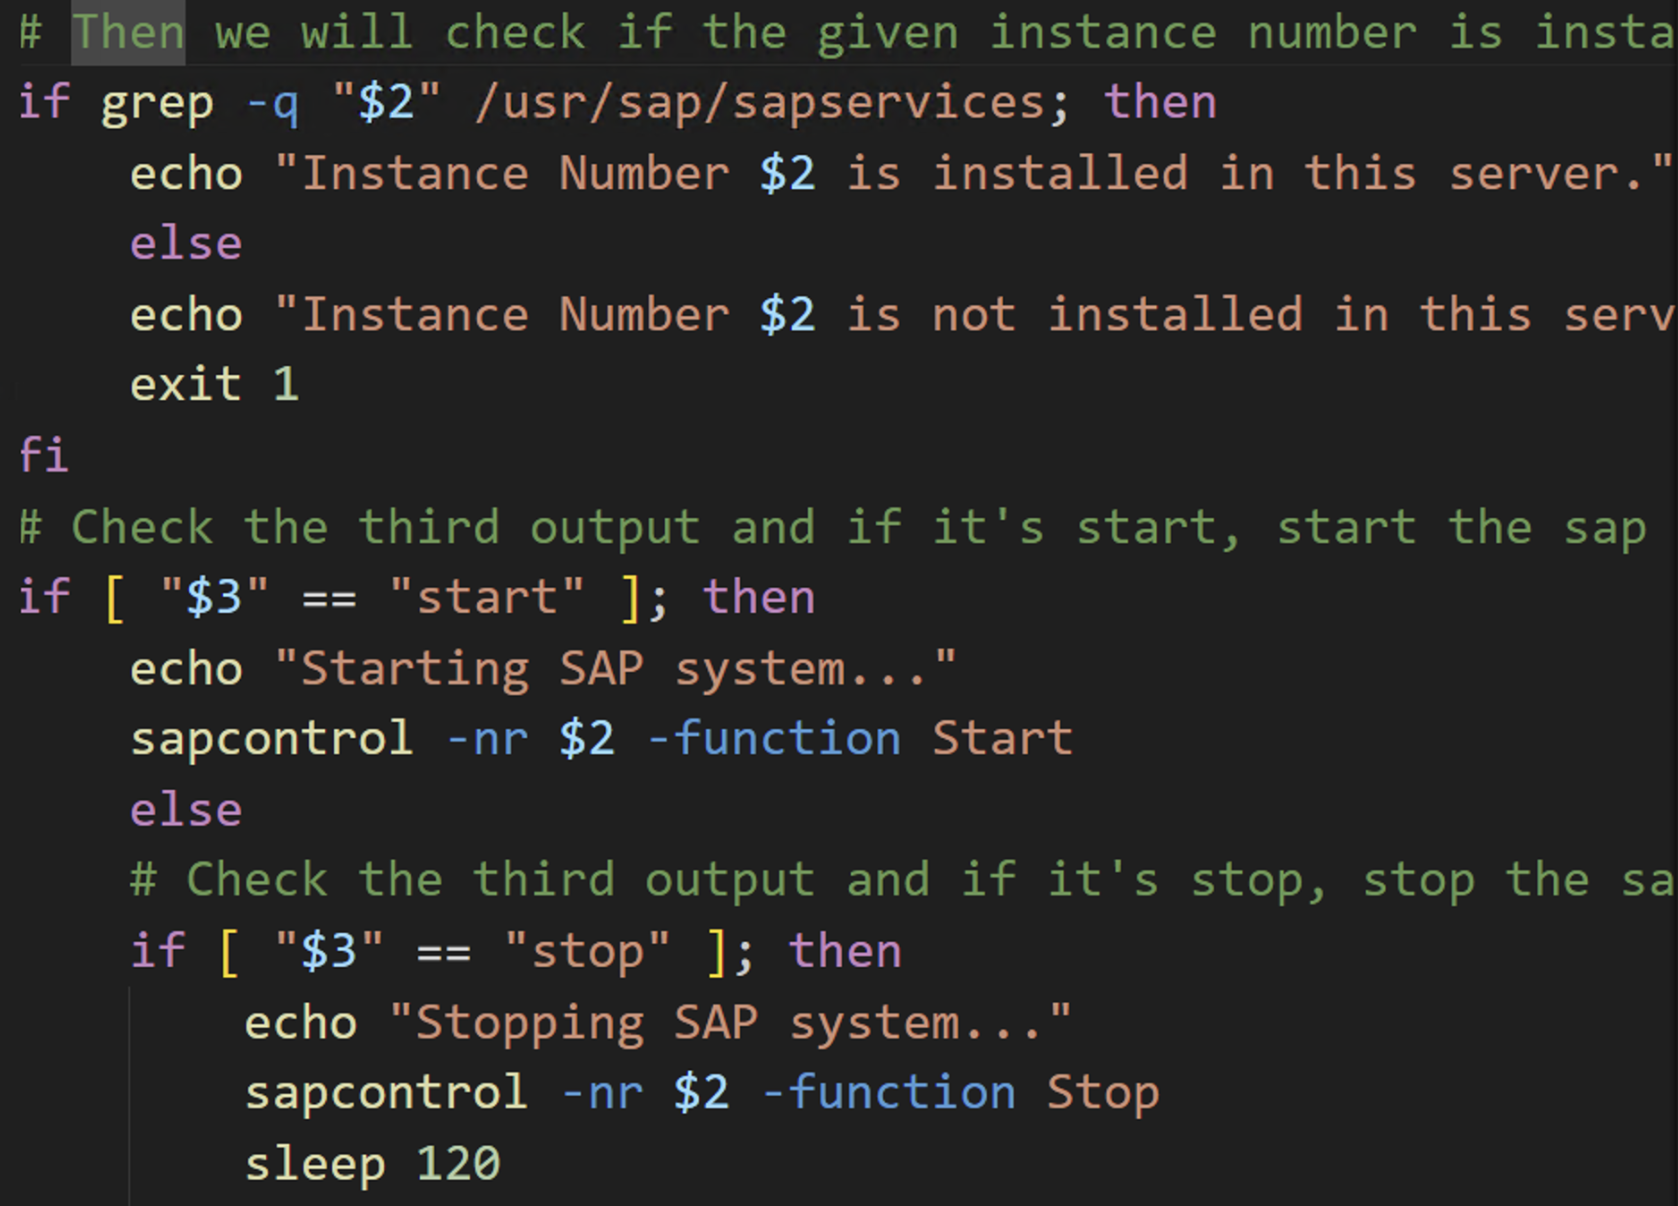
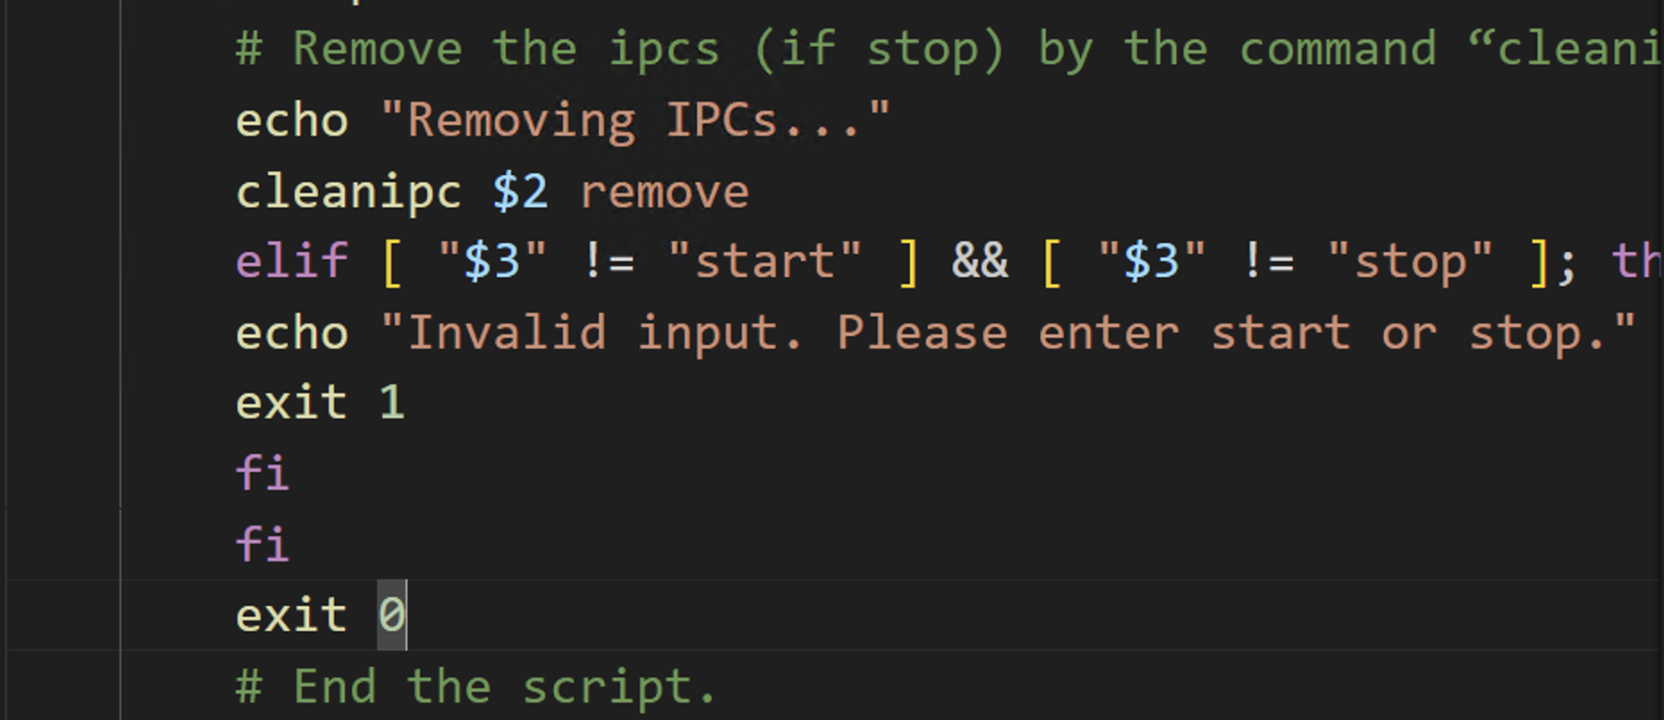
6.     Once you accept the code, Q will propose the next lines. Keep accepting the appropriate lines of code until all required sections are completed.  Once the script is ready, it should look similar to what is depicted below.  Save the script.

Figure 4 – First part of the script

Figure 5 – Second part of the script

Figure 6 – Third part of the script

7.     Go to the EC2 instance hosting SAP and use your local text editor (e.g., vi) to create a file with the  “.sh” file extension. Let’s say the file is named SAPStopStart.sh

8.     Paste the contents of the code from your file in the IDE.

9.     Save the file and add execute permissions to the file by running chmod +x SAPStopStart.sh

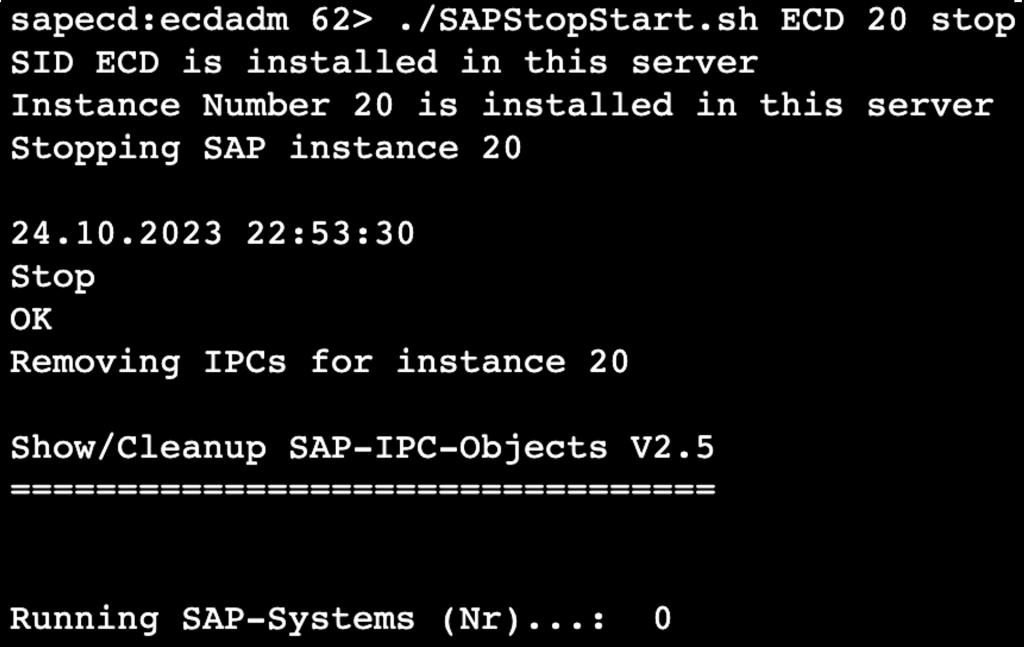
10.   To run the script, use the appropriate arguments as shown below.

SAPStopStart.sh <SID> <InstanceNumber> <start/stop>


Figure 7 – Running the script

Conclusion

Although in this blog post we used a simple example of starting and stopping an SAP system, Amazon Q Developer can be extended to a broader spectrum of SAP operational scenarios. Q Developer’s capabilities can be used to harness a broad range of SAP-related use cases, such as kernel patching, database patching, and beyond. In addition to code suggestions, Q Developer offers a security scanning feature, which can be used for fortifying application security. Amazon Q Developer is available in Pro and Free Tiers and does not require an AWS Account to get started.  For the purpose of this blog, we used the Amazon Q Developer Free Tier.  To learn more about Amazon Q Developer, click to go to its product page.

GitHub Availability Report: May 2024

Post Syndicated from Jakub Oleksy original https://github.blog/2024-06-12-github-availability-report-may-2024/

In May, we experienced one incident that resulted in significant degraded performance across GitHub services.

May 21 11:40 UTC (lasting 7 hours 26 minutes)

On May 21, various GitHub services experienced latency due to a configuration change in an upstream cloud provider. GitHub Copilot Chat experienced p50 latency of up to 2.5s and p95 latency of up to 6s, GitHub Actions was degraded with 20 60 minute delays for workflow run updates, and GitHub Enterprise Importer customers experienced longer migration run times due to Actions delays.

Actions users experienced their runs stuck in stale states for some time even if the underlying runner was completed successfully, and Copilot Chat users experienced delays in receiving responses to their requests. Billing related metrics for budget notifications and UI reporting were also delayed, leading to outdated billing details. No data was lost and reporting was restored after mitigation.

We determined that the issue was caused by a scheduled operating system upgrade that resulted in unintended and uneven distribution of traffic within the cluster. A short- term strategy of increasing the number of network routes between our data centers and cloud provider helped mitigate the incident.

To prevent recurrence of the incidents, we have identified and are fixing gaps in our monitoring and alerting for load thresholds to improve both detection and mitigation time.


Please follow our status page for real-time updates on status changes and post-incident recaps. To learn more about what we’re working on, check out the GitHub Engineering Blog.

The post GitHub Availability Report: May 2024 appeared first on The GitHub Blog.

Cockpit project releases Cockpit Files plugin

Post Syndicated from jzb original https://lwn.net/Articles/978156/

The Cockpit project has
announced
the first release of Cockpit
Files, a plugin for Cockpit that allows file management on your server
via a web browser:

Cockpit Files was initially started by Google Summer of Code (GSoC)
student Mahmoud Hamdy
and is now under active development by the Cockpit team. The goal is
to replace the functionality of the cockpit-navigator
plugin from 45Drives and include automated testing per commit, a
standard PatternFly-based interface, and consistency with the rest of
Cockpit.

Development builds for Fedora are available via a
Copr repository
, and packages are expected for Arch, Debian, and
Fedora. LWN covered the
Cockpit project in March.

Ingest and analyze your data using Amazon OpenSearch Service with Amazon OpenSearch Ingestion

Post Syndicated from Sharmila Shanmugam original https://aws.amazon.com/blogs/big-data/ingest-and-analyze-your-data-using-amazon-opensearch-service-with-amazon-opensearch-ingestion/

In today’s data-driven world, organizations are continually confronted with the task of managing extensive volumes of data securely and efficiently. Whether it’s customer information, sales records, or sensor data from Internet of Things (IoT) devices, the importance of handling and storing data at scale with ease of use is paramount.

A common use case that we see amongst customers is to search and visualize data. In this post, we show how to ingest CSV files from Amazon Simple Storage Service (Amazon S3) into Amazon OpenSearch Service using the Amazon OpenSearch Ingestion feature and visualize the ingested data using OpenSearch Dashboards.

OpenSearch Service is a fully managed, open source search and analytics engine that helps you with ingesting, searching, and analyzing large datasets quickly and efficiently. OpenSearch Service enables you to quickly deploy, operate, and scale OpenSearch clusters. It continues to be a tool of choice for a wide variety of use cases such as log analytics, real-time application monitoring, clickstream analysis, website search, and more.

OpenSearch Dashboards is a visualization and exploration tool that allows you to create, manage, and interact with visuals, dashboards, and reports based on the data indexed in your OpenSearch cluster.

Visualize data in OpenSearch Dashboards

Visualizing the data in OpenSearch Dashboards involves the following steps:

  • Ingest data – Before you can visualize data, you need to ingest the data into an OpenSearch Service index in an OpenSearch Service domain or Amazon OpenSearch Serverless collection and define the mapping for the index. You can specify the data types of fields and how they should be analyzed; if nothing is specified, OpenSearch Service automatically detects the data type of each field and creates a dynamic mapping for your index by default.
  • Create an index pattern – After you index the data into your OpenSearch Service domain, you need to create an index pattern that enables OpenSearch Dashboards to read the data stored in the domain. This pattern can be based on index names, aliases, or wildcard expressions. You can configure the index pattern by specifying the timestamp field (if applicable) and other settings that are relevant to your data.
  • Create visualizations – You can create visuals that represent your data in meaningful ways. Common types of visuals include line charts, bar charts, pie charts, maps, and tables. You can also create more complex visualizations like heatmaps and geospatial representations.

Ingest data with OpenSearch Ingestion

Ingesting data into OpenSearch Service can be challenging because it involves a number of steps, including collecting, converting, mapping, and loading data from different data sources into your OpenSearch Service index. Traditionally, this data was ingested using integrations with Amazon Data Firehose, Logstash, Data Prepper, Amazon CloudWatch, or AWS IoT.

The OpenSearch Ingestion feature of OpenSearch Service introduced in April 2023 makes ingesting and processing petabyte-scale data into OpenSearch Service straightforward. OpenSearch Ingestion is a fully managed, serverless data collector that allows you to ingest, filter, enrich, and route data to an OpenSearch Service domain or OpenSearch Serverless collection. You configure your data producers to send data to OpenSearch Ingestion, which automatically delivers the data to the domain or collection that you specify. You can configure OpenSearch Ingestion to transform your data before delivering it.

OpenSearch Ingestion scales automatically to meet the requirements of your most demanding workloads, helping you focus on your business logic while abstracting away the complexity of managing complex data pipelines. It’s powered by Data Prepper, an open source streaming Extract, Transform, Load (ETL) tool that can filter, enrich, transform, normalize, and aggregate data for downstream analysis and visualization.

OpenSearch Ingestion uses pipelines as a mechanism that consists of three major components:

  • Source – The input component of a pipeline. It defines the mechanism through which a pipeline consumes records.
  • Processors – The intermediate processing units that can filter, transform, and enrich records into a desired format before publishing them to the sink. The processor is an optional component of a pipeline.
  • Sink – The output component of a pipeline. It defines one or more destinations to which a pipeline publishes records. A sink can also be another pipeline, which allows you to chain multiple pipelines together.

You can process data files written in S3 buckets in two ways: by processing the files written to Amazon S3 in near real time using Amazon Simple Queue Service (Amazon SQS), or with the scheduled scans approach, in which you process the data files in batches using one-time or recurring scheduled scan configurations.

In the following section, we provide an overview of the solution and guide you through the steps to ingest CSV files from Amazon S3 into OpenSearch Service using the S3-SQS approach in OpenSearch Ingestion. Additionally, we demonstrate how to visualize the ingested data using OpenSearch Dashboards.

Solution overview

The following diagram outlines the workflow of ingesting CSV files from Amazon S3 into OpenSearch Service.

solution_overview

The workflow comprises the following steps:

  1. The user uploads CSV files into Amazon S3 using techniques such as direct upload on the AWS Management Console or AWS Command Line Interface (AWS CLI), or through the Amazon S3 SDK.
  2. Amazon SQS receives an Amazon S3 event notification as a JSON file with metadata such as the S3 bucket name, object key, and timestamp.
  3. The OpenSearch Ingestion pipeline receives the message from Amazon SQS, loads the files from Amazon S3, and parses the CSV data from the message into columns. It then creates an index in the OpenSearch Service domain and adds the data to the index.
  4. Lastly, you create an index pattern and visualize the ingested data using OpenSearch Dashboards.

OpenSearch Ingestion provides a serverless ingestion framework to effortlessly ingest data into OpenSearch Service with just a few clicks.

Prerequisites

Make sure you meet the following prerequisites:

Create an SQS queue

Amazon SQS offers a secure, durable, and available hosted queue that lets you integrate and decouple distributed software systems and components. Create a standard SQS queue and provide a descriptive name for the queue, then update the access policy by navigating to the Amazon SQS console, opening the details of your queue, and editing the policy on the Advanced tab.

The following is a sample access policy you could use for reference to update the access policy:

{
  "Version": "2008-10-17",
  "Id": "example-ID",
  "Statement": [
    {
      "Sid": "example-statement-ID",
      "Effect": "Allow",
      "Principal": {
        "Service": "s3.amazonaws.com"
      },
      "Action": "SQS:SendMessage",
      "Resource": "<SQS_QUEUE_ARN>"
    }
  ]
}

SQS FIFO (First-In-First-Out) queues aren’t supported as an Amazon S3 event notification destination. To send a notification for an Amazon S3 event to an SQS FIFO queue, you can use Amazon EventBridge.

create_sqs_queue

Create an S3 bucket and enable Amazon S3 event notification

Create an S3 bucket that will be the source for CSV files and enable Amazon S3 notifications. The Amazon S3 notification invokes an action in response to a specific event in the bucket. In this workflow, whenever there in an event of type S3:ObjectCreated:*, the event sends an Amazon S3 notification to the SQS queue created in the previous step. Refer to Walkthrough: Configuring a bucket for notifications (SNS topic or SQS queue) to configure the Amazon S3 notification in your S3 bucket.

create_s3_bucket

Create an IAM policy for the OpenSearch Ingest pipeline

Create an AWS Identity and Access Management (IAM) policy for the OpenSearch pipeline with the following permissions:

  • Read and delete rights on Amazon SQS
  • GetObject rights on Amazon S3
  • Describe domain and ESHttp rights on your OpenSearch Service domain

The following is an example policy:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": "es:DescribeDomain",
      "Resource": "<OPENSEARCH_SERVICE_DOMAIN_ENDPOINT>:domain/*"
    },
    {
      "Effect": "Allow",
      "Action": "es:ESHttp*",
      "Resource": "<OPENSEARCH_SERVICE_DOMAIN_ENDPOINT>/*"
    },
    {
      "Effect": "Allow",
      "Action": "s3:GetObject",
      "Resource": "<S3_BUCKET_ARN>/*"
    },
    {
      "Effect": "Allow",
      "Action": [
        "sqs:DeleteMessage",
        "sqs:ReceiveMessage"
      ],
      "Resource": "<SQS_QUEUE_ARN>"
    }
  ]
}

create_policy

Create an IAM role and attach the IAM policy

A trust relationship defines which entities (such as AWS accounts, IAM users, roles, or services) are allowed to assume a particular IAM role. Create an IAM role for the OpenSearch Ingestion pipeline (osis-pipelines.amazonaws.com), attach the IAM policy created in the previous step, and add the trust relationship to allow OpenSearch Ingestion pipelines to write to domains.

create_iam_role

Configure an OpenSearch Ingestion pipeline

A pipeline is the mechanism that OpenSearch Ingestion uses to move data from its source (where the data comes from) to its sink (where the data goes). OpenSearch Ingestion provides out-of-the-box configuration blueprints to help you quickly set up pipelines without having to author a configuration from scratch. Set up the S3 bucket as the source and OpenSearch Service domain as the sink in the OpenSearch Ingestion pipeline with the following blueprint:

version: '2'
s3-pipeline:
  source:
    s3:
      acknowledgments: true
      notification_type: sqs
      compression: automatic
      codec:
        newline: 
          #header_destination: <column_names>
      sqs:
        queue_url: <SQS_QUEUE_URL>
      aws:
        region: <AWS_REGION>
        sts_role_arn: <STS_ROLE_ARN>
  processor:
    - csv:
        column_names_source_key: column_names
        column_names:
          - row_id
          - order_id
          - order_date
          - date_key
          - contact_name
          - country
          - city
          - region
          - sub_region
          - customer
          - customer_id
          - industry
          - segment
          - product
          - license
          - sales
          - quantity
          - discount
          - profit
    - convert_entry_type:
        key: sales
        type: double
    - convert_entry_type:
        key: profit
        type: double
    - convert_entry_type:
        key: discount
        type: double
    - convert_entry_type:
        key: quantity
        type: integer
    - date:
        match:
          - key: order_date
            patterns:
              - MM/dd/yyyy
        destination: order_date_new
  sink:
    - opensearch:
        hosts:
          - <OPEN_SEARCH_SERVICE_DOMAIN_ENDPOINT>
        index: csv-ingest-index
        aws:
          sts_role_arn: <STS_ROLE_ARN>
          region: <AWS_REGION>

On the OpenSearch Service console, create a pipeline with the name my-pipeline. Keep the default capacity settings and enter the preceding pipeline configuration in the Pipeline configuration section.

Update the configuration setting with the previously created IAM roles to read from Amazon S3 and write into OpenSearch Service, the SQS queue URL, and the OpenSearch Service domain endpoint.

create_pipeline

Validate the solution

To validate this solution, you can use the dataset SaaS-Sales.csv. This dataset contains transaction data from a software as a service (SaaS) company selling sales and marketing software to other companies (B2B). You can initiate this workflow by uploading the SaaS-Sales.csv file to the S3 bucket. This invokes the pipeline and creates an index in the OpenSearch Service domain you created earlier.

Follow these steps to validate the data using OpenSearch Dashboards.

First, you create an index pattern. An index pattern is a way to define a logical grouping of indexes that share a common naming convention. This allows you to search and analyze data across all matching indexes using a single query or visualization. For example, if you named your indexes csv-ingest-index-2024-01-01 and csv-ingest-index-2024-01-02 while ingesting the monthly sales data, you can define an index pattern as csv-* to encompass all these indexes.

create_index_pattern

Next, you create a visualization.  Visualizations are powerful tools to explore and analyze data stored in OpenSearch indexes. You can gather these visualizations into a real time OpenSearch dashboard. An OpenSearch dashboard provides a user-friendly interface for creating various types of visualizations such as charts, graphs, maps, and dashboards to gain insights from data.

You can visualize the sales data by industry with a pie chart with the index pattern created in the previous step. To create a pie chart, update the metrics details as follows on the Data tab:

  • Set Metrics to Slice
  • Set Aggregation to Sum
  • Set Field to sales

create_dashboard

To view the industry-wise sales details in the pie chart, add a new bucket on the Data tab as follows:

  • Set Buckets to Split Slices
  • Set Aggregation to Terms
  • Set Field to industry.keyword

create_pie_chart

You can visualize the data by creating more visuals in the OpenSearch dashboard.

add_visuals

Clean up

When you’re done exploring OpenSearch Ingestion and OpenSearch Dashboards, you can delete the resources you created to avoid incurring further costs.

Conclusion

In this post, you learned how to ingest CSV files efficiently from S3 buckets into OpenSearch Service with the OpenSearch Ingestion feature in a serverless way without requiring a third-party agent. You also learned how to analyze the ingested data using OpenSearch dashboard visualizations. You can now explore extending this solution to build OpenSearch Ingestion pipelines to load your data and derive insights with OpenSearch Dashboards.


About the Authors

Sharmila Shanmugam is a Solutions Architect at Amazon Web Services. She is passionate about solving the customers’ business challenges with technology and automation and reduce the operational overhead. In her current role, she helps customers across industries in their digital transformation journey and build secure, scalable, performant and optimized workloads on AWS.

Harsh Bansal is an Analytics Solutions Architect with Amazon Web Services. In his role, he collaborates closely with clients, assisting in their migration to cloud platforms and optimizing cluster setups to enhance performance and reduce costs. Before joining AWS, he supported clients in leveraging OpenSearch and Elasticsearch for diverse search and log analytics requirements.

Rohit Kumar works as a Cloud Support Engineer in the Support Engineering team at Amazon Web Services. He focuses on Amazon OpenSearch Service, offering guidance and technical help to customers, helping them create scalable, highly available, and secure solutions on AWS Cloud. Outside of work, Rohit enjoys watching or playing cricket. He also loves traveling and discovering new places. Essentially, his routine revolves around eating, traveling, cricket, and repeating the cycle.

How Swisscom automated Amazon Redshift as part of their One Data Platform solution using AWS CDK – Part 2

Post Syndicated from Asad Bin Imtiaz original https://aws.amazon.com/blogs/big-data/how-swisscom-automated-amazon-redshift-as-part-of-their-one-data-platform-solution-using-aws-cdk-part-2/

In this series, we talk about Swisscom’s journey of automating Amazon Redshift provisioning as part of the Swisscom One Data Platform (ODP) solution using the AWS Cloud Development Kit (AWS CDK), and we provide code snippets and the other useful references.

In Part 1, we did a deep dive on provisioning a secure and compliant Redshift cluster using the AWS CDK and the best practices of secret rotation. We also explained how Swisscom used AWS CDK custom resources to automate the creation of dynamic user groups that are relevant for the AWS Identity and Access Management (IAM) roles matching different job functions.

In this post, we explore using the AWS CDK and some of the key topics for self-service usage of the provisioned Redshift cluster by end-users as well as other managed services and applications. These topics include federation with the Swisscom identity provider (IdP), JDBC connections, detective controls using AWS Config rules and remediation actions, cost optimization using the Redshift scheduler, and audit logging.

Scheduled actions

To optimize cost-efficiency for provisioned Redshift cluster deployments, Swisscom implemented a scheduling mechanism. This functionality is driven by the user configuration of the cluster, as described in Part 1 of this series, wherein the user may enable dynamic pausing and resuming of clusters based on specified cron expressions:

redshift_options:
...
  use_scheduler: true                                         # Whether to use Redshift scheduler
  scheduler_pause_cron: "cron(00 18 ? * MON-FRI *)"           # Cron expression for scheduler pause
  scheduler_resume_cron: "cron(00 08 ? * MON-FRI *)"          # Cron expression for scheduler resume
...

This feature allows Swisscom to reduce operational costs by suspending cluster activity during off-peak hours. This leads to significant cost savings by pausing and resuming clusters at appropriate times. The scheduling is achieved using the AWS CloudFormation action CfnScheduledAction. The following code illustrates how Swisscom implemented this scheduling:

if config.use_scheduler:
    cfn_scheduled_action_pause = aws_redshift.CfnScheduledAction(
        scope, "schedule-pause-action",
        # ...
        schedule=config.scheduler_pause_cron,
        # ...
        target_action=aws_redshift.CfnScheduledAction.ScheduledActionTypeProperty(
                         pause_cluster=aws_redshift.CfnScheduledAction.ResumeClusterMessageProperty(
                            cluster_identifier='cluster-identifier'
                         )
                      )
    )

    cfn_scheduled_action_resume = aws_redshift.CfnScheduledAction(
        scope, "schedule-resume-action",
        # ...
        schedule=config.scheduler_resume_cron,
        # ...
        target_action=aws_redshift.CfnScheduledAction.ScheduledActionTypeProperty(
                         resume_cluster=aws_redshift.CfnScheduledAction.ResumeClusterMessageProperty(
                            cluster_identifier='cluster-identifier'
                         )
                      )
    )

JDBC connections

The JDBC connectivity for Amazon Redshift clusters was also very flexible, adapting to user-defined subnet types and security groups in the configuration:

redshift_options:
...
  subnet_type: "routable-private"         # 'routable-private' OR 'non-routable-private'
  security_group_id: "sg-test_redshift"   # Security Group ID for Amazon Redshift (referenced group must exists in Account)
...

As illustrated in the ODP architecture diagram in Part 1 of this series, a considerable part of extract, transform, and load (ETL) processes is anticipated to operate outside of Amazon Redshift, within the serverless AWS Glue environment. Given this, Swisscom needed a mechanism for AWS Glue to connect to Amazon Redshift. This connectivity to Redshift clusters is provided through JDBC by creating an AWS Glue connection within the AWS CDK code. This connection allows ETL processes to interact with the Redshift cluster by establishing a JDBC connection. The subnet and security group defined in the user configuration guide the creation of JDBC connectivity. If no security groups are defined in the configuration, a default one is created. The connection is configured with details of the data product from which the Redshift cluster is being provisioned, like ETL user and default database, along with network elements like cluster endpoint, security group, and subnet to use, providing secure and efficient data transfer. The following code snippet demonstrates how this was achieved:

jdbc_connection = glue.Connection(
    scope, "redshift-glue-connection",
    type=ConnectionType("JDBC"),
    connection_name="redshift-glue-connection",
    subnet=connection_subnet,
    security_groups=connection_security_groups,
    properties={
        "JDBC_CONNECTION_URL": f"jdbc:redshift://{cluster_endpoint}/{database_name}",
        "USERNAME": etl_user.username,
        "PASSWORD": etl_user.password.to_string(),
        "redshiftTmpDir": f"s3://{data_product_name}-redshift-work"
    }
)

By doing this, Swisscom made sure that serverless ETL workflows in AWS Glue can securely communicate with newly provisioned Redshift cluster running within a secured virtual private cloud (VPC).

Identity federation

Identity federation allows a centralized system (the IdP) to be used for authenticating users in order to access a service provider like Amazon Redshift. A more general overview of the topic can be found in Identity Federation in AWS.

Identity federation not only enhances security due to its centralized user lifecycle management and centralized authentication mechanism (for example, supporting multi-factor authentication), but also improves the user experience and reduces the overall complexity of identity and access management and thereby also its governance.

In Swisscom’s setup, Microsoft Active Directory Services are used for identity and access management. At the initial build stages of ODP, Amazon Redshift offered two different options for identity federation:

In Swisscom’s context, during the initial implementation, Swisscom opted for IAM-based SAML 2.0 IdP federation because this is a more general approach, which can also be used for other AWS services, such as Amazon QuickSight (see Setting up IdP federation using IAM and QuickSight).

At 2023 AWS re:Invent, AWS announced a new connection option to Amazon Redshift based on AWS IAM Identity Center. IAM Identity Center provides a single place for workforce identities in AWS, allowing the creation of users and groups directly within itself or by federation with standard IdPs like Okta, PingOne, Microsoft Entra ID (Azure AD), or any IdP that supports SAML 2.0 and SCIM. It also provides a single sign-on (SSO) experience for Redshift features and other analytics services such as Amazon Redshift Query Editor V2 (see Integrate Identity Provider (IdP) with Amazon Redshift Query Editor V2 using AWS IAM Identity Center for seamless Single Sign-On), QuickSight, and AWS Lake Formation. Moreover, a single IAM Identity Center instance can be shared with multiple Redshift clusters and workgroups with a simple auto-discovery and connect capability. It makes sure all Redshift clusters and workgroups have a consistent view of users, their attributes, and groups. This whole setup fits well with ODP’s vision of providing self-service analytics across the Swisscom workforce with necessary security controls in place. At the time of writing, Swisscom is actively working towards using IAM Identity Center as the standard federation solution for ODP. The following diagram illustrates the high-level architecture for the work in progress.

Audit logging

Amazon Redshift audit logging is useful for auditing for security purposes, monitoring, and troubleshooting. The logging provides information, such as the IP address of the user’s computer, the type of authentication used by the user, or the timestamp of the request. Amazon Redshift logs the SQL operations, including connection attempts, queries, and changes, and makes it straightforward to track the changes. These logs can be accessed through SQL queries against system tables, saved to a secure Amazon Simple Storage Service (Amazon S3) location, or exported to Amazon CloudWatch.

Amazon Redshift logs information in the following log files:

  • Connection log – Provides information to monitor users connecting to the database and related connection information like their IP address.
  • User log – Logs information about changes to database user definitions.
  • User activity log – Tracks information about the types of queries that both the users and the system perform in the database. It’s useful primarily for troubleshooting purposes.

With the ODP solution, Swisscom wanted to write all the Amazon Redshift logs to CloudWatch. This is currently not directly supported by the AWS CDK, so Swisscom implemented a workaround solution using the AWS CDK custom resources option, which invokes the SDK on the Redshift action enableLogging. See the following code:

    custom_resources.AwsCustomResource(self, f"{self.cluster_identifier}-custom-sdk-logging",
           on_update=custom_resources.AwsSdkCall(
               service="Redshift",
               action="enableLogging",
               parameters={
                   "ClusterIdentifier": self.cluster_identifier,
                   "LogDestinationType": "cloudwatch",
                   "LogExports": ["connectionlog","userlog","useractivitylog"],
               },
               physical_resource_id=custom_resources.PhysicalResourceId.of(
                   f"{self.account}-{self.region}-{self.cluster_identifier}-logging")
           ),
           policy=custom_resources.AwsCustomResourcePolicy.from_sdk_calls(
               resources=[f"arn:aws:redshift:{self.region}:{self.account}:cluster:{self.cluster_identifier}"]
           )
        )

AWS Config rules and remediation

After a Redshift cluster has been deployed, Swisscom needed to make sure that the cluster meets the governance rules defined in every point in time after creation. For that, Swisscom decided to use AWS Config.

AWS Config provides a detailed view of the configuration of AWS resources in your AWS account. This includes how the resources are related to one another and how they were configured in the past so you can see how the configurations and relationships change over time.

An AWS resource is an entity you can work with in AWS, such as an Amazon Elastic Compute Cloud (Amazon EC2) instance, Amazon Elastic Block Store (Amazon EBS) volume, security group, or Amazon VPC.

The following diagram illustrates the process Swisscom implemented.

If an AWS Config rule isn’t compliant, a remediation can be applied. Swisscom defined the pause cluster action as default in case of a non-compliant cluster (based on your requirements, other remediation actions are possible). This is covered using an AWS Systems Manager automation document (SSM document).

Automation, a capability of Systems Manager, simplifies common maintenance, deployment, and remediation tasks for AWS services like Amazon EC2, Amazon Relational Database Service (Amazon RDS), Amazon Redshift, Amazon S3, and many more.

The SSM document is based on the AWS document AWSConfigRemediation-DeleteRedshiftCluster. It looks like the following code:

description: | 
  ### Document name - PauseRedshiftCluster-WithCheck 

  ## What does this document do? 
  This document pauses the given Amazon Redshift cluster using the [PauseCluster](https://docs.aws.amazon.com/redshift/latest/APIReference/API_PauseCluster.html) API. 

  ## Input Parameters 
  * AutomationAssumeRole: (Required) The ARN of the role that allows Automation to perform the actions on your behalf. 
  * ClusterIdentifier: (Required) The identifier of the Amazon Redshift Cluster. 

  ## Output Parameters 
  * PauseRedshiftClusterWithoutSnapShot.Response: The standard HTTP response from the PauseCluster API. 
  * PauseRedshiftClusterWithSnapShot.Response: The standard HTTP response from the PauseCluster API. 
schemaVersion: '0.3' 
assumeRole: '{{ AutomationAssumeRole }}' 
parameters: 
  AutomationAssumeRole: 
    type: String 
    description: (Required) The ARN of the role that allows Automation to perform the actions on your behalf. 
    allowedPattern: '^arn:aws[a-z0-9-]*:iam::\d{12}:role\/[\w-\/.@+=,]{1,1017}$' 
  ClusterIdentifier: 
    type: String 
    description: (Required) The identifier of the Amazon Redshift Cluster. 
    allowedPattern: '[a-z]{1}[a-z0-9_.-]{0,62}' 
mainSteps: 
  - name: GetRedshiftClusterStatus 
    action: 'aws:executeAwsApi' 
    inputs: 
      ClusterIdentifier: '{{ ClusterIdentifier }}' 
      Service: redshift 
      Api: DescribeClusters 
    description: |- 
      ## GetRedshiftClusterStatus 
      Gets the status for the given Amazon Redshift Cluster. 
    outputs: 
      - Name: ClusterStatus 
        Selector: '$.Clusters[0].ClusterStatus' 
        Type: String 
    timeoutSeconds: 600 
  - name: Condition 
    action: 'aws:branch' 
    inputs: 
      Choices: 
        - NextStep: PauseRedshiftCluster 
          Variable: '{{ GetRedshiftClusterStatus.ClusterStatus }}' 
          StringEquals: available 
      Default: Finish 
  - name: PauseRedshiftCluster 
    action: 'aws:executeAwsApi' 
    description: | 
      ## PauseRedshiftCluster 
      Makes PauseCluster API call using Amazon Redshift Cluster identifier and pauses the cluster without taking any final snapshot. 
      ## Outputs 
      * Response: The standard HTTP response from the PauseCluster API. 
    timeoutSeconds: 600 
    isEnd: false 
    nextStep: VerifyRedshiftClusterPause 
    inputs: 
      Service: redshift 
      Api: PauseCluster 
      ClusterIdentifier: '{{ ClusterIdentifier }}' 
    outputs: 
      - Name: Response 
        Selector: $ 
        Type: StringMap 
  - name: VerifyRedshiftClusterPause 
    action: 'aws:assertAwsResourceProperty' 
    timeoutSeconds: 600 
    isEnd: true 
    description: | 
      ## VerifyRedshiftClusterPause 
      Verifies the given Amazon Redshift Cluster is paused. 
    inputs: 
      Service: redshift 
      Api: DescribeClusters 
      ClusterIdentifier: '{{ ClusterIdentifier }}' 
      PropertySelector: '$.Clusters[0].ClusterStatus' 
      DesiredValues: 
        - pausing 
  - name: Finish 
    action: 'aws:sleep' 
    inputs: 
      Duration: PT1S 
    isEnd: true

The SSM automations document is deployed with the AWS CDK:

from aws_cdk import aws_ssm as ssm  

ssm_document_content = #read yaml document as dict  

document_id = 'automation_id'   
document_name = 'automation_name' 

document = ssm.CfnDocument(scope, id=document_id, content=ssm_document_content,  
                           document_format="YAML", document_type='Automation', name=document_name) 

To run the automation document, AWS Config needs the right permissions. You can create an IAM role for this purpose:

from aws_cdk import iam 

#Create role for the automation 
role_name = 'role-to-pause-redshift'
automation_role = iam.Role(scope, 'role-to-pause-redshift-cluster', 
                           assumed_by=iam.ServicePrincipal('ssm.amazonaws.com'), 
                           role_name=role_name) 

automation_policy = iam.Policy(scope, "policy-to-pause-cluster", 
                               policy_name='policy-to-pause-cluster', 
                               statements=[ 
                                   iam.PolicyStatement( 
                                       effect=iam.Effect.ALLOW, 
                                       actions=['redshift:PauseCluster', 
                                                'redshift:DescribeClusters'], 
                                       resources=['*'] 
                                   ) 
                               ]) 

automation_role.attach_inline_policy(automation_policy) 

Swisscom defined the rules to be applied following AWS best practices (see Security Best Practices for Amazon Redshift). These are deployed as AWS Config conformance packs. A conformance pack is a collection of AWS Config rules and remediation actions that can be quickly deployed as a single entity in an AWS account and AWS Region or across an organization in AWS Organizations.

Conformance packs are created by authoring YAML templates that contain the list of AWS Config managed or custom rules and remediation actions. You can also use SSM documents to store your conformance pack templates on AWS and directly deploy conformance packs using SSM document names.

This AWS conformance pack can be deployed using the AWS CDK:

from aws_cdk import aws_config  
  
conformance_pack_template = # read yaml file as str 
conformance_pack_content = # substitute `role_arn_for_substitution` and `document_for_substitution` in conformance_pack_template

conformance_pack_id = 'conformance-pack-id' 
conformance_pack_name = 'conformance-pack-name' 


conformance_pack = aws_config.CfnConformancePack(scope, id=conformance_pack_id, 
                                                 conformance_pack_name=conformance_pack_name, 
                                                 template_body=conformance_pack_content) 

Conclusion

Swisscom is building its next-generation data-as-a-service platform through a combination of automated provisioning processes, advanced security features, and user-configurable options to cater for diverse data handling and data products’ needs. The integration of the Amazon Redshift construct in the ODP framework is a significant stride in Swisscom’s journey towards a more connected and data-driven enterprise landscape.

In Part 1 of this series, we demonstrated how to provision a secure and compliant Redshift cluster using the AWS CDK as well as how to deal with the best practices of secret rotation. We also showed how to use AWS CDK custom resources in automating the creation of dynamic user groups that are relevant for the IAM roles matching different job functions.

In this post, we showed, through the usage of the AWS CDK, how to address key Redshift cluster usage topics such as federation with the Swisscom IdP, JDBC connections, detective controls using AWS Config rules and remediation actions, cost optimization using the Redshift scheduler, and audit logging.

The code snippets in this post are provided as is and will need to be adapted to your specific use cases. Before you get started, we highly recommend speaking to an Amazon Redshift specialist.


About the Authors

Asad bin Imtiaz is an Expert Data Engineer at Swisscom, with over 17 years of experience in architecting and implementing enterprise-level data solutions.

Jesús Montelongo Hernández is an Expert Cloud Data Engineer at Swisscom. He has over 20 years of experience in IT systems, data warehousing, and data engineering.

Samuel Bucheli is a Lead Cloud Architect at Zühlke Engineering AG. He has over 20 years of experience in software engineering, software architecture, and cloud architecture.

Srikanth Potu is a Senior Consultant in EMEA, part of the Professional Services organization at Amazon Web Services. He has over 25 years of experience in Enterprise data architecture, databases and data warehousing.

How Swisscom automated Amazon Redshift as part of their One Data Platform solution using AWS CDK – Part 1

Post Syndicated from Asad Bin Imtiaz original https://aws.amazon.com/blogs/big-data/how-swisscom-automated-amazon-redshift-as-part-of-their-one-data-platform-solution-using-aws-cdk-part-1/

Swisscom is a leading telecommunications provider in Switzerland. Swisscom’s Data, Analytics, and AI division is building a One Data Platform (ODP) solution that will enable every Swisscom employee, process, and product to benefit from the massive value of Swisscom’s data.

In a two-part series, we talk about Swisscom’s journey of automating Amazon Redshift provisioning as part of the Swisscom ODP solution using the AWS Cloud Development Kit (AWS CDK), and we provide code snippets and the other useful references.

In this post, we deep dive into provisioning a secure and compliant Redshift cluster using the AWS CDK and discuss the best practices of secret rotation. We also explain how Swisscom used AWS CDK custom resources in automating the creation of dynamic user groups that are relevant for the AWS Identity and Access management (IAM) roles matching different job functions.

In Part 2 of this series, we explore using the AWS CDK and some of the key topics for self-service usage of the provisioned Redshift cluster by end-users as well as other managed services and applications. These topics include federation with the Swisscom identity provider (IdP), JDBC connections, detective controls using AWS Config rules and remediation actions, cost optimization using the Redshift scheduler, and audit logging.

Amazon Redshift is a fast, scalable, secure, fully managed, and petabyte scale data warehousing service empowering organizations and users to analyze massive volumes of data using standard SQL tools. Amazon Redshift benefits from seamless integration with many AWS services, such as Amazon Simple Storage Service (Amazon S3), AWS Key Management Service (AWS KMS), IAM, and AWS Lake Formation, to name a few.

The AWS CDK helps you build reliable, scalable, and cost-effective applications in the cloud with the considerable expressive power of a programming language. The AWS CDK supports TypeScript, JavaScript, Python, Java, C#/.Net, and Go. Developers can use one of these supported programming languages to define reusable cloud components known as constructs. A data product owner in Swisscom can use the ODP AWS CDK libraries with a simple config file to provision ready-to-use infrastructure, such as S3 buckets; AWS Glue ETL (extract, transform, and load) jobs, Data Catalog databases, and crawlers; Redshift clusters; JDBC connections; and more, with all the needed permissions in just a few minutes.

One Data Platform

The ODP architecture is based on the AWS Well Architected Framework Analytics Lens and follows the pattern of having raw, standardized, conformed, and enriched layers as described in Modern data architecture. By using infrastructure as code (IaC) tools, ODP enables self-service data access with unified data management, metadata management (data catalog), and standard interfaces for analytics tools with a high degree of automation by providing the infrastructure, integrations, and compliance measures out of the box. At the same time, the ODP will also be continuously evolving and adapting to the constant stream of new additional features being added to the AWS analytics services. The following high-level architecture diagram shows ODP with different layers of the modern data architecture. In this series, we specifically discuss the components specific to Amazon Redshift (highlighted in red).

Harnessing Amazon Redshift for ODP

A pivotal decision in the data warehousing migration process involves evaluating the extent of a lift-and-shift approach vs. re-architecture. Balancing system performance, scalability, and cost while taking into account the rigid system pieces requires a strategic solution. In this context, Amazon Redshift has stood out as a cloud-centered data warehousing solution, especially with its straightforward and seamless integration into the modern data architecture. Its straightforward integration and fluid compatibility with AWS services like Amazon QuickSight, Amazon SageMaker, and Lake Formation further solidifies its choice for forward-thinking data warehousing strategies. As a columnar database, it’s particularly well suited for consumer-oriented data products. Consequently, Swisscom chose to provide a solution wherein use case-specific Redshift clusters are provisioned using IaC, specifically using the AWS CDK.

A crucial aspect of Swisscom’s strategy is the integration of these data domain and use case-oriented individual clusters into a virtually single and unified data environment, making sure that data ingestion, transformation, and eventual data product sharing remains convenient and seamless. This is achieved by custom provisioning of the Redshift clusters based on user or use case needs, in a shared virtual private cloud (VPC), with data and system governance policies and remediation, IdP federation, and Lake Formation integration already in place.

Although many controls for governance and security were put in place in the AWS CDK construct, Swisscom users also have the flexibility to customize their clusters based on what they need. The cluster configurator allows users to define the cluster characteristics based on individual use case requirements while remaining within the bounds of defined best practices. The key configurable parameters include node types, sizing, subnet types for routing based on different security policies per user case, enabling scheduler, integration with IdP setup, and any additional post-provisioning setup, like the creation of specific schemas and group-level access on it. This flexibility in configuration is achieved for the Amazon Redshift AWS CDK construct through a Python data class, which serves as a template for users to specify aspects like subnet types, scheduler cron expressions, and specific security groups for the cluster, among other configurations. Users are also able to select the type of subnets (routable-private or non-routable-private) to adhere to network security policies and architectural standards. See the following data class options:

class RedShiftOptions:
    node_type: NodeType
    number_of_nodes: int
    vpc_id: str
    security_group_id: Optional[str]
    subnet_type: SubnetType
    use_redshift_scheduler: bool
    scheduler_pause_cron: str
    scheduler_resume_cron: str
    maintenance_window: str
    # Additional configuration options ...

The separation of configuration in the RedShiftOptions data class from the cluster provisioning logic in the RedShiftCluster AWS CDK construct is in line with AWS CDK best practices, wherein both constructs and stacks should accept a property object to allow for full configurability completely in code. This separates the concerns of configuration and resource creation, enhancing the readability and maintainability. The data class structure reflects the user configuration from a configuration file, making it straightforward for users to specify their requirements. The following code shows what the configuration file for the Redshift construct looks like:

# ===============================
# Amazon Redshift Options
# ===============================
# The enriched layer is based on Amazon Redshift.
# This section has properties for Amazon Redshift.
#
redshift_options:
  provision_cluster: true                                     # Skip provisioning Amazon Redshift in enriched layer (required)
  number_of_nodes: 2                                          # Number of nodes for redshift cluster to provision (optional) (default = 2)
  node_type: "ra3.xlplus"                                     # Type of the cluster nodes (optional) (default = "ra3.xlplus")
  use_scheduler: true                                        # Whether to use the Amazon Redshift scheduler (optional)
  scheduler_pause_cron: "cron(00 18 ? * MON-FRI *)"           # Cron expression for scheduler pause (optional)
  scheduler_resume_cron: "cron(00 08 ? * MON-FRI *)"          # Cron expression for scheduler resume (optional)
  maintenance_window: "sun:23:45-mon:00:15"                   # Maintenance window for Amazon Redshift (optional)
  subnet_type: "routable-private"                             # 'routable-private' OR 'non-routable-private' (optional)
  security_group_id: "sg-test-redshift"                       # Security group ID for Amazon Redshift (optional) (reference must exist)
  user_groups:                                                # User groups and their privileges on default DB
    - group_name: dba
      access: [ 'ALL' ]
    - group_name: data_engineer
      access: [ 'SELECT' , 'INSERT' , 'UPDATE' , 'DELETE' , 'TRUNCATE' ]
    - group_name: qa_engineer
      access: [ 'SELECT' ]
  integrate_all_groups_with_idp: false

Admin user secret rotation

As part of the cluster deployment, an admin user is created with its credentials stored in AWS Secrets Manager for database management. This admin user is used for automating several setup operations, such as the setup of database schemas and integration with Lake Formation. For the admin user, as well as other users created for Amazon Redshift, Swisscom used AWS KMS for encryption of the secrets associated with cluster users. The use of Secrets Manager made it simple to adhere to IAM security best practices by supporting the automatic rotation of credentials. Such a setup can be quickly implemented on the AWS Management Console or may be integrated in AWS CDK code with friendly methods in the aws_redshift_alpha module. This module provides higher-level constructs (specifically, Layer 2 constructs), including convenience and helper methods, as well as sensible default values. This module is experimental and under active development and may have changes that aren’t backward compatible. See the following admin user code:

admin_secret_kms_key_options = KmsKeyOptions(
    ...
    key_name='redshift-admin-secret',
    service="secretsmanager"
)
admin_secret_kms_key = aws_kms.Key(
    scope, 'AdminSecretKmsKey,
    # ...
)

# ...

cluster = aws_redshift_alpha.Cluster(
            scope, cluster_identifier,
            # ...
            master_user=aws_redshift_alpha.Login(
                master_username='admin',
                encryption_key=admin_secret_kms_key
                ),
            default_database_name=database_name,
            # ...
        )

See the following code for secret rotation:

self.cluster.add_rotation_single_user(aws_cdk.Duration.days(60))

Methods such as add_rotation_single_user internally rely on a serverless application hosted in the AWS Serverless Application Model repository, which may be in a different AWS Region outside of the organization’s permission boundary. To effectively use such functions, make sure access to this serverless repository within the organization’s service control policies. If the access is not feasible, consider implementing solutions such as custom AWS Lambda functions replicating these functionalities (within your organization’s permission boundary).

AWS CDK custom resource

A key challenge Swisscom faced was automating the creation of dynamic user groups tied to specific IAM roles at deployment time. As an initial and simple solution, Swisscom’s approach was creating an AWS CDK custom resource using the admin user to submit and run SQL statements. This allowed Swisscom to embed the logic for the database schema, user group assignments, and Lake Formation-specific configurations directly within AWS CDK code, making sure that these crucial steps are automatically handled during cluster deployment. See the following code:

sql = get_rendered_stacked_sqls()

custom_resources.AwsCustomResource(scope, 'RedshiftSQLCustomResource',
                                           on_update=custom_resources.AwsSdkCall(
                                               service='RedshiftData',
                                               action='executeStatement',
                                               parameters={
                                                   'ClusterIdentifier': cluster_identifier,
                                                   'SecretArn': secret_arn,
                                                   'Database': database_name,
                                                   'Sql': f'{sqls}',
                                               },
                                               physical_resource_id=custom_resources.PhysicalResourceId.of(
                                                   f'{account}-{region}-{cluster_identifier}-groups')
                                           ),
                                           policy=custom_resources.AwsCustomResourcePolicy.from_sdk_calls(
                                               resources=[f'arn:aws:redshift:{region}:{account}:cluster:{cluster_identifier}']
                                           )
                                        )


cluster.secret.grant_read(groups_cr)

This method of dynamic SQL, embedded within the AWS CDK code, provides a unified deployment and post-setup of the Redshift cluster in a convenient manner. Although this approach unifies the deployment and post-provisioning configuration with SQL-based operations, it remains an initial strategy. It is tailored for convenience and efficiency in the current context. As ODP further evolves, Swisscom will iterate this solution to streamline SQL operations during cluster provisioning. Swisscom remains open to integrating external schema management tools or similar approaches where they add value.

Another aspect of Swisscom’s architecture is the dynamic creation of IAM roles tailored for the user groups for different job functions within the Amazon Redshift environment. This IAM role generation is also driven by the user configuration, acting as a blueprint for dynamically defining user role to policy mappings. This allowed them to quickly adapt to evolving requirements. The following code illustrates the role assignment:

policy_mappings = {
    "role1": ["Policy1", "Policy2"],
    "role2": ["Policy3", "Policy4"],
    ...
    # Example:
    # "dba-role": ["AmazonRedshiftFullAccess", "CloudWatchFullAccess"],
    # ...
}

def create_redshift_role(role_name, policy_list):
   # Implementation to create Redshift role with provided policies
   ...

redshift_role_1 = create_redshift_role(
    data_product_name, "role1", policy_names=policy_mappings["role1"])
redshift_role_1 = create_redshift_role(
    data_product_name, "role1", policy_names=policy_mappings["role1"])
# Example:
# redshift_dba_role = create_redshift_role(
#   data_product_name, "dba-role", policy_names=policy_mappings["dba-role"])
...

Conclusion

Swisscom is building its data-as-a-service platform, and Amazon Redshift has a crucial role as part of the solution. In this post, we discussed the aspects that need to be covered in your IaC best practices to deploy secure and maintainable Redshift clusters using the AWS CDK. Although Amazon Redshift supports industry-leading security, there are aspects organizations need to adjust to their specific requirements. It is therefore important to define the configurations and best practices that are right for your organization and bring it to your IaC to make it available for your end consumers.

We also discussed how to provision a secure and compliant Redshift cluster using the AWS CDK and deal with the best practices of secret rotation. We also showed how to use AWS CDK custom resources in automating the creation of dynamic user groups that are relevant for the IAM roles matching different job functions.

In Part 2 of this series, we will delve into enhancing self-service capabilities for end-users. We will cover topics like integration with the Swisscom IdP, setting up JDBC connections, and implementing detective controls and remediation actions, among others.

The code snippets in this post are provided as is and will need to be adapted to your specific use cases. Before you get started, we highly recommend speaking to an Amazon Redshift specialist.


About the Authors

Asad bin Imtiaz is an Expert Data Engineer at Swisscom, with over 17 years of experience in architecting and implementing enterprise-level data solutions.

Jesús Montelongo Hernández is an Expert Cloud Data Engineer at Swisscom. He has over 20 years of experience in IT systems, data warehousing, and data engineering.

Samuel Bucheli is a Lead Cloud Architect at Zühlke Engineering AG. He has over 20 years of experience in software engineering, software architecture, and cloud architecture.

Srikanth Potu is a Senior Consultant in EMEA, part of the Professional Services organization at Amazon Web Services. He has over 25 years of experience in Enterprise data architecture, databases and data warehousing.
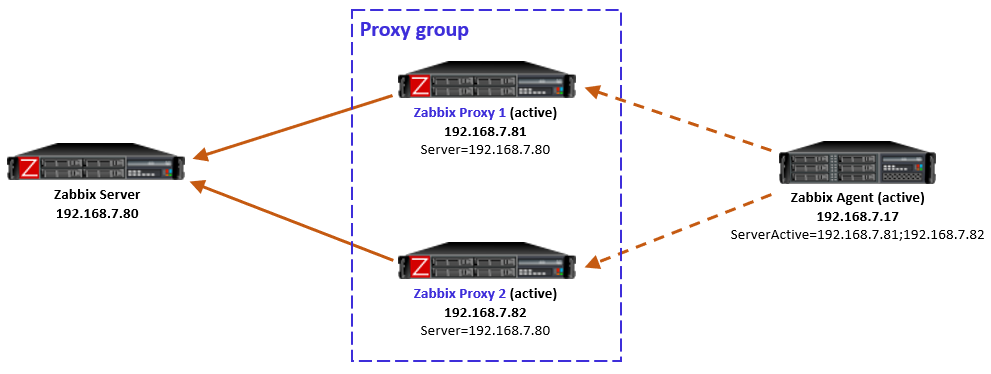
[$] Elevating CentOS 7 to a new life

Post Syndicated from jzb original https://lwn.net/Articles/977762/

CentOS Linux 7 was first
released
in July 2014, and is due to go end-of-life (EOL) on June 30.
By now, anyone who pays attention to such things is aware that Red Hat pulled the plug on
CentOS Linux in late 2020 to be replaced by CentOS Stream
instead. CentOS Linux 8
support was wound
down
at the end of 2021 rather than in 2029 as originally stated.
CentOS Linux 7 was allowed to serve out its
full lifespan—but that EOL is approaching rapidly and
there’s no direct upgrade path. Users and organizations looking for a lifeline might want to consider
AlmaLinux’s ELevate
utility, which allows CentOS users to migrate to alternate enterprise
Linux (EL) operating systems.

Nominations are open for the PSF Board election

Post Syndicated from jzb original https://lwn.net/Articles/978149/

The Python Software
Foundation
(PSF) has announced
that nominations are open for the PSF Board election through June
25:

Who runs for the board? People who care about the Python community,
who want to see it flourish and grow, and also have a few hours a
month to attend regular meetings, serve on committees, participate in
conversations, and promote the Python community.

The PSF has a video about
serving on the board for those who might be interested. PSF members
can nominate themselves or another member. Candidates
will be announced on June 27. Voting begins on July 2 and will end on
July 16.

[$] Memory sealing for the GNU C Library

Post Syndicated from corbet original https://lwn.net/Articles/978010/

The mseal() system call allows a
process to prevent any future changes to portions of its address space
(thus “sealing” them); it was patterned after the mimmutable() system call in OpenBSD.
mseal() generated a lot of discussion, but it was finally merged
for the upcoming 6.10 kernel release. While mseal() was initially
aimed at securing the Chrome browser, the hope was that it would be useful
elsewhere; as a step toward realizing that hope, Adhemerval Zanella has
posted a
patch series
adding support for — and use of — mseal() to the
GNU C library (glibc).

The collective thoughts of the interwebz