Tag Archives: Uncategorized

Friday Squid Blogging: Squid and Efficient Solar Tech

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/friday-squid-blogging-squid-and-efficient-solar-tech.html

Researchers are trying to use squid color-changing biochemistry for solar tech.

This appears to be new and related research to a 2019 squid post.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

AI Vulnerability Finding

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/ai-vulnerability-finding.html

Microsoft is reporting that its AI systems are able to find new vulnerabilities in source code:

Microsoft discovered eleven vulnerabilities in GRUB2, including integer and buffer overflows in filesystem parsers, command flaws, and a side-channel in cryptographic comparison.

Additionally, 9 buffer overflows in parsing SquashFS, EXT4, CramFS, JFFS2, and symlinks were discovered in U-Boot and Barebox, which require physical access to exploit.

The newly discovered flaws impact devices relying on UEFI Secure Boot, and if the right conditions are met, attackers can bypass security protections to execute arbitrary code on the device.

Nothing major here. These aren’t exploitable out of the box. But that an AI system can do this at all is impressive, and I expect their capabilities to continue to improve.

Reimagining Democracy

Post Syndicated from B. Schneier original https://www.schneier.com/blog/archives/2025/04/reimagining-democracy-2.html

Imagine that all of us—all of society—have landed on some alien planet and need to form a government: clean slate. We do not have any legacy systems from the United States or any other country. We do not have any special or unique interests to perturb our thinking. How would we govern ourselves? It is unlikely that we would use the systems we have today. Modern representative democracy was the best form of government that eighteenth-century technology could invent. The twenty-first century is very different: scientifically, technically, and philosophically. For example, eighteenth-century democracy was designed under the assumption that travel and communications were both hard.

Indeed, the very idea of representative government was a hack to get around technological limitations. Voting is easier now. Does it still make sense for all of us living in the same place to organize every few years and choose one of us to go to a single big room far away and make laws in our name? Representative districts are organized around geography because that was the only way that made sense two hundred-plus years ago. But we do not need to do it that way anymore. We could organize representation by age: one representative for the thirty-year-olds, another for the forty-year-olds, and so on. We could organize representation randomly: by birthday, perhaps. We can organize in any way we want. American citizens currently elect people to federal posts for terms ranging from two to six years. Would ten years be better for some posts? Would ten days be better for others? There are lots of possibilities. Maybe we can make more use of direct democracy by way of plebiscites. Certainly we do not want all of us, individually, to vote on every amendment to every bill, but what is the optimal balance between votes made in our name and ballot initiatives that we all vote on?

For the past three years, I have organized a series of annual two-day workshops to discuss these and other such questions.1 For each event, I brought together fifty people from around the world: political scientists, economists, law professors, experts in artificial intelligence, activists, government types, historians, science-fiction writers, and more. We did not come up with any answers to our questions—and I would have been surprised if we had—but several themes emerged from the event. Misinformation and propaganda was a theme, of course, and the inability to engage in rational policy discussions when we cannot agree on facts. The deleterious effects of optimizing a political system for economic outcomes was another theme. Given the ability to start over, would anyone design a system of government for the near-term financial interest of the wealthiest few? Another theme was capitalism and how it is or is not intertwined with democracy. While the modern market economy made a lot of sense in the industrial age, it is starting to fray in the information age. What comes after capitalism, and how will it affect the way we govern ourselves?

Many participants examined the effects of technology, especially artificial intelligence (AI). We looked at whether—and when—we might be comfortable ceding power to an AI system. Sometimes deciding is easy. I am happy for an AI system to figure out the optimal timing of traffic lights to ensure the smoothest flow of cars through my city. When will we be able to say the same thing about the setting of interest rates? Or taxation? How would we feel about an AI device in our pocket that voted in our name, thousands of times per day, based on preferences that it inferred from our actions? Or how would we feel if an AI system could determine optimal policy solutions that balanced every voter’s preferences: Would it still make sense to have a legislature and representatives? Possibly we should vote directly for ideas and goals instead, and then leave the details to the computers.

These conversations became more pointed in the second and third years of our workshop, after generative AI exploded onto the internet. Large language models are poised to write laws, enforce both laws and regulations, act as lawyers and judges, and plan political strategy. How this capacity will compare to human expertise and capability is still unclear, but the technology is changing quickly and dramatically. We will not have AI legislators anytime soon, but just as today we accept that all political speeches are professionally written by speechwriters, will we accept that future political speeches will all be written by AI devices? Will legislators accept AI-written legislation, especially when that legislation includes a level of detail that human-based legislation generally does not? And if so, how will that change affect the balance of power between the legislature and the administrative state? Most interestingly, what happens when the AI tools we use to both write and enforce laws start to suggest policy options that are beyond human understanding? Will we accept them, because they work? Or will we reject a system of governance where humans are only nominally in charge?

Scale was another theme of the workshops. The size of modern governments reflects the technology at the time of their founding. European countries and the early American states are a particular size because that was a governable size in the eighteenth and nineteenth centuries. Larger governments—those of the United States as a whole and of the European Union—reflect a world where travel and communications are easier. Today, though, the problems we have are either local, at the scale of cities and towns, or global. Do we really have need for a political unit the size of France or Virginia? Or is it a mixture of scales that we really need, one that moves effectively between the local and the global?

As to other forms of democracy, we discussed one from history and another made possible by today’s technology. Sortition is a system of choosing political officials randomly. We use it today when we pick juries, but both the ancient Greeks and some cities in Renaissance Italy used it to select major political officials. Today, several countries—largely in Europe—are using the process to decide policy on complex issues. We might randomly choose a few hundred people, representative of the population, to spend a few weeks being briefed by experts, debating the issues, and then deciding on environmental regulations, or a budget, or pretty much anything.

“Liquid democracy” is a way of doing away with elections altogether. The idea is that everyone has a vote and can assign it to anyone they choose. A representative collects the proxies assigned to him or her and can either vote directly on the issues or assign all the proxies to someone else. Perhaps proxies could be divided: this person for economic matters, another for health matters, a third for national defense, and so on. In the purer forms of this system, people might transfer their votes to someone else at any time. There would be no more election days: vote counts might change every day.

And then, there is the question of participation and, more generally, whose interests are taken into account. Early democracies were really not democracies at all; they limited participation by gender, race, and land ownership. These days, to achieve a more comprehensive electorate we could lower the voting age. But, of course, even children too young to vote have rights, and in some cases so do other species. Should future generations be given a “voice,” whatever that means? What about nonhumans, or whole ecosystems? Should everyone have the same volume and type of voice? Right now, in the United States, the very wealthy have much more influence than others do. Should we encode that superiority explicitly? Perhaps younger people should have a more powerful vote than everyone else. Or maybe older people should.

In the workshops, those questions led to others about the limits of democracy. All democracies have boundaries limiting what the majority can decide. We are not allowed to vote Common Knowledge out of existence, for example, but can generally regulate speech to some degree. We cannot vote, in an election, to jail someone, but we can craft laws that make a particular action illegal. We all have the right to certain things that cannot be taken away from us. In the community of our future, what should be our rights as individuals? What should be the rights of society, superseding those of individuals?

Personally, I was most interested, at each of the three workshops, in how political systems fail. As a security technologist, I study how complex systems are subverted—hacked, in my parlance—for the benefit of a few at the expense of the many. Think of tax loopholes, or tricks to avoid government regulation. These hacks are common today, and AI tools will make them easier to find—and even to design—in the future. I would want any government system to be resistant to trickery. Or, to put it another way: I want the interests of each individual to align with the interests of the group at every level. We have never had a system of government with this property, but—in a time of existential risks such as climate change—it is important that we develop one.

Would this new system of government even be called “democracy”? I truly do not know.

Such speculation is not practical, of course, but still is valuable. Our workshops did not produce final answers and were not intended to do so. Our discourse was filled with suggestions about how to patch our political system where it is fraying. People regularly debate changes to the US Electoral College, or the process of determining voting districts, or the setting of term limits. But those are incremental changes. It is difficult to find people who are thinking more radically: looking beyond the horizon—not at what is possible today but at what may be possible eventually. Thinking incrementally is critically important, but it is also myopic. It represents a hill-climbing strategy of continuous but quite limited improvements. We also need to think about discontinuous changes that we cannot easily get to from here; otherwise, we may be forever stuck at local maxima. And while true innovation in politics is a lot harder than innovation in technology, especially without a violent revolution forcing changes on us, it is something that we as a species are going to have to get good at, one way or another.

Our workshop will reconvene for a fourth meeting in December 2025.

Note

  1. The First International Workshop on Reimagining Democracy (IWORD) was held December 7—8, 2022. The Second IWORD was held December 12—13, 2023. Both took place at the Harvard Kennedy School. The sponsors were the Ford Foundation, the Knight Foundation, and the Ash and Belfer Centers of the Kennedy School. See Schneier, “Recreating Democracy” and Schneier, “Second Interdisciplinary Workshop.”

This essay was originally published in Common Knowledge.

Speaking Your Language: Expanded language support in Amazon Q Developer

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/amazon-q-developer-global-capabilities/

As the world of software development becomes increasingly global, the need for tools that support multiple languages has become paramount. Today, I am excited to announce expanded language support in Amazon Q Developer. In this post, I explore the recent expansion of language support in Amazon Q Developer, a powerful platform used by developers worldwide to discuss architecture, create documentation, design interfaces, and build applications.

While English remains the lingua franca of programming, the reality of modern software development extends far beyond code. Developers worldwide use Amazon Q Developer to discuss architecture decisions, create documentation, design user interfaces, and build applications that serve global audiences. By expanding language support, Amazon Q Developer now enables developers to have more natural, fluid conversations about complex technical concepts in their preferred language, whether they’re designing system architecture, generating documentation, or planning application localization strategies.

The power of this expanded language support is demonstrated in the following image, where I asked the same container hosting question in English, Chinese, Hindi, and Spanish. Not only does Amazon Q Developer now provide complete responses in these languages, but it also maintains technical accuracy while adapting to linguistic nuances. Furthermore, Q Developer now suggests follow-up questions and responses in the user’s chosen language, creating a more intuitive and seamless experience for developers worldwide. This natural flow of conversation in any language helps maintain the developer’s focus and flow, eliminating the mental overhead of constant translation.

Four screenshots of Amazon Q chat interface showing the same conversation about hosting containers on AWS in different languages - English, Chinese, Hindi, and Spanish. Each screenshot displays Q&A format with detailed explanations about AWS container hosting options, focusing on Amazon Elastic Container Service (ECS) and including code snippets for container deployment.

Expanded language is available in the integrated development environment (IDE) and command line interface (CLI) with support coming to the AWS Management Console soon. In my IDE, chat, inline chat, inline suggestions, agents, etc. now support additional spoken languages. In the following example, I used inline chat to ask, in French, that Q Developer add TSDocs comments to my code. As you can see, Q Developer added comments, in French, documenting the method.

Code snippet showing error handling in JavaScript/TypeScript. The code includes JSDoc comments in French explaining fatal error management in the main function, followed by a catch block that logs the error and exits the process with code 1.

Whether you’re a developer in Seoul writing documentation in Korean, a startup in Madrid brainstorming architecture in Spanish, or a team in Brazil collaborating in Portuguese, Amazon Q Developer is now ready to support your journey and your preferred language. Expanded language support is available to users of both the Free and Pro Tier starting today. Get started with Amazon Q Developer, and share your feedback. Together, we’re building a more inclusive and accessible future for software development.

What Powers the Performance of Backblaze

Post Syndicated from Tina Cessna original https://www.backblaze.com/blog/what-powers-the-performance-of-backblaze/

A decorative image showing objects around the cloud.

At Backblaze, we’re in the business of building a storage platform that can handle billions of operations a day—reliably, predictably, and fast. That means digging deep into low-level architecture, optimizing what most people overlook, and constantly balancing trade-offs between performance, cost, and scale.

Today, we’re kicking off a new blog series that showcases the platform-level work our Engineering team has been doing to build and run a modern cloud storage platform. The kind of work that usually stays buried in Jira tickets and internal docs, but that makes all the difference when you’re serving exabytes at scale.

What it really means to build a modern cloud storage platform

When people talk about cloud storage, they usually focus on capacity, availability, and price. This includes the systems, tools, and architectural decisions that enable our infrastructure to scale reliably while handling billions of operations per day.

We’re crafting a dynamic, evolving platform that handles exabytes of data with reliability and efficiency. We’re a platform that developers and businesses build on. That means durability, performance, uptime, and predictability aren’t just nice-to-haves—they’re fundamental requirements. As Senior Vice President of Engineering, I’m excited to pull back the curtain and offer a glimpse into the ongoing engineering efforts that power our platform.

Building for simple is more complex than it seems

One of our core engineering philosophies is this: Complexity should serve simplicity. For example, changing how we handle request headers might sound like a small thing, but when you operate a distributed system at scale, even tiny inefficiencies can multiply quickly. A 5% improvement in API response time might not sound dramatic, but at exabyte scale, that translates to millions of faster interactions per day, less CPU usage, and better customer experiences across the board.

Our Engineering team is always thinking about those compound effects. Sometimes that means rewriting parts of a system that have been stable for years. Other times it means saying no to flashy solutions and choosing battle-tested designs that will hold up under load.

What to expect from this series

If you care about performance, distributed architecture, or what it actually takes to run a reliable cloud infrastructure, this is for you. We’ve published deep dives before, such as our articles on Load Balancing (and Load Balancing 2.0!), improvements on small file uploads that gave us speeds faster than AWS, Network Stats, Reed-Solomon erasure coding, using native code in Backblaze Personal Backup, everything that lives in the Backblaze Github, and many, many more. 

Our goal, in addition to talking about the individual stories, is to start talking about some of the throughlines—when one project spawns another, or how we decide which project to pursue when there are competing priorities. 

These projects don’t usually make headlines on their own, but taken together, they form the backbone of what makes Backblaze perform the way it does. They’ll become part of our regularly scheduled programming, and we’ll drop them in our Tech Lab category so you can find them easily.

Sign up for the Developer newsletter

Sign up for the Backblaze Developer Newsletter to receive a monthly roundup of articles and news for everyone developing on Backblaze B2 Cloud Storage.

Sign Up Here ➔ 

See you on the next one—and let us know if you have questions

We’re proud of the work our engineers are doing, but more than that, we think it’s worth sharing. Whether you’re a fellow cloud architect, a developer using our platform, or just someone curious about what it takes to run cloud infrastructure at scale, we hope this series offers something insightful. 

Technology doesn’t stand still, and neither do we. The more efficient our platform becomes, the better we can serve our customers—and the more we can invest in new ideas. So stay tuned. We’re kicking things off in this content series in the next few weeks, and we look forward to hearing your thoughts!

The post What Powers the Performance of Backblaze appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Arguing Against CALEA

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/arguing-against-calea.html

At a Congressional hearing earlier this week, Matt Blaze made the point that CALEA, the 1994 law that forces telecoms to make phone calls wiretappable, is outdated in today’s threat environment and should be rethought:

In other words, while the legally-mandated CALEA capability requirements have changed little over the last three decades, the infrastructure that must implement and protect it has changed radically. This has greatly expanded the “attack surface” that must be defended to prevent unauthorized wiretaps, especially at scale. The job of the illegal eavesdropper has gotten significantly easier, with many more options and opportunities for them to exploit. Compromising our telecommunications infrastructure is now little different from performing any other kind of computer intrusion or data breach, a well-known and endemic cybersecurity problem. To put it bluntly, something like Salt Typhoon was inevitable, and will likely happen again unless significant changes are made.

This is the access that the Chinese threat actor Salt Typhoon used to spy on Americans:

The Wall Street Journal first reported Friday that a Chinese government hacking group dubbed Salt Typhoon broke into three of the largest U.S. internet providers, including AT&T, Lumen (formerly CenturyLink), and Verizon, to access systems they use for facilitating customer data to law enforcement and governments. The hacks reportedly may have resulted in the “vast collection of internet traffic”; from the telecom and internet giants. CNN and The Washington Post also confirmed the intrusions and that the U.S. government’s investigation is in its early stages.

DIRNSA Fired

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/dirnsa-fired.html

In “Secrets and Lies” (2000), I wrote:

It is poor civic hygiene to install technologies that could someday facilitate a police state.

It’s something a bunch of us were saying at the time, in reference to the vast NSA’s surveillance capabilities.

I have been thinking of that quote a lot as I read news stories of President Trump firing the Director of the National Security Agency. General Timothy Haugh.

A couple of weeks ago, I wrote:

We don’t know what pressure the Trump administration is using to make intelligence services fall into line, but it isn’t crazy to worry that the NSA might again start monitoring domestic communications.

The NSA already spies on Americans in a variety of ways. But that’s always been a sideline to its main mission: spying on the rest of the world. Once Trump replaces Haugh with a loyalist, the NSA’s vast surveillance apparatus can be refocused domestically.

Giving that agency all those powers in the 1990s, in the 2000s after the terrorist attacks of 9/11, and in the 2010s was always a mistake. I fear that we are about to learn how big a mistake it was.

Here’s PGP creator Phil Zimmerman in 1996, spelling it out even more clearly:

The Clinton Administration seems to be attempting to deploy and entrench a communications infrastructure that would deny the citizenry the ability to protect its privacy. This is unsettling because in a democracy, it is possible for bad people to occasionally get elected—sometimes very bad people. Normally, a well-functioning democracy has ways to remove these people from power. But the wrong technology infrastructure could allow such a future government to watch every move anyone makes to oppose it. It could very well be the last government we ever elect.

When making public policy decisions about new technologies for the government, I think one should ask oneself which technologies would best strengthen the hand of a police state. Then, do not allow the government to deploy those technologies. This is simply a matter of good civic hygiene.

Web 3.0 Requires Data Integrity

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/web-3-0-requires-data-integrity.html

If you’ve ever taken a computer security class, you’ve probably learned about the three legs of computer security—confidentiality, integrity, and availability—known as the CIA triad. When we talk about a system being secure, that’s what we’re referring to. All are important, but to different degrees in different contexts. In a world populated by artificial intelligence (AI) systems and artificial intelligent agents, integrity will be paramount.

What is data integrity? It’s ensuring that no one can modify data—that’s the security angle—but it’s much more than that. It encompasses accuracy, completeness, and quality of data—all over both time and space. It’s preventing accidental data loss; the “undo” button is a primitive integrity measure. It’s also making sure that data is accurate when it’s collected—that it comes from a trustworthy source, that nothing important is missing, and that it doesn’t change as it moves from format to format. The ability to restart your computer is another integrity measure.

The CIA triad has evolved with the Internet. The first iteration of the Web—Web 1.0 of the 1990s and early 2000s—prioritized availability. This era saw organizations and individuals rush to digitize their content, creating what has become an unprecedented repository of human knowledge. Organizations worldwide established their digital presence, leading to massive digitization projects where quantity took precedence over quality. The emphasis on making information available overshadowed other concerns.

As Web technologies matured, the focus shifted to protecting the vast amounts of data flowing through online systems. This is Web 2.0: the Internet of today. Interactive features and user-generated content transformed the Web from a read-only medium to a participatory platform. The increase in personal data, and the emergence of interactive platforms for e-commerce, social media, and online everything demanded both data protection and user privacy. Confidentiality became paramount.

We stand at the threshold of a new Web paradigm: Web 3.0. This is a distributed, decentralized, intelligent Web. Peer-to-peer social-networking systems promise to break the tech monopolies’ control on how we interact with each other. Tim Berners-Lee’s open W3C protocol, Solid, represents a fundamental shift in how we think about data ownership and control. A future filled with AI agents requires verifiable, trustworthy personal data and computation. In this world, data integrity takes center stage.

For example, the 5G communications revolution isn’t just about faster access to videos; it’s about Internet-connected things talking to other Internet-connected things without our intervention. Without data integrity, for example, there’s no real-time car-to-car communications about road movements and conditions. There’s no drone swarm coordination, smart power grid, or reliable mesh networking. And there’s no way to securely empower AI agents.

In particular, AI systems require robust integrity controls because of how they process data. This means technical controls to ensure data is accurate, that its meaning is preserved as it is processed, that it produces reliable results, and that humans can reliably alter it when it’s wrong. Just as a scientific instrument must be calibrated to measure reality accurately, AI systems need integrity controls that preserve the connection between their data and ground truth.

This goes beyond preventing data tampering. It means building systems that maintain verifiable chains of trust between their inputs, processing, and outputs, so humans can understand and validate what the AI is doing. AI systems need clean, consistent, and verifiable control processes to learn and make decisions effectively. Without this foundation of verifiable truth, AI systems risk becoming a series of opaque boxes.

Recent history provides many sobering examples of integrity failures that naturally undermine public trust in AI systems. Machine-learning (ML) models trained without thought on expansive datasets have produced predictably biased results in hiring systems. Autonomous vehicles with incorrect data have made incorrect—and fatal—decisions. Medical diagnosis systems have given flawed recommendations without being able to explain themselves. A lack of integrity controls undermines AI systems and harms people who depend on them.

They also highlight how AI integrity failures can manifest at multiple levels of system operation. At the training level, data may be subtly corrupted or biased even before model development begins. At the model level, mathematical foundations and training processes can introduce new integrity issues even with clean data. During execution, environmental changes and runtime modifications can corrupt previously valid models. And at the output level, the challenge of verifying AI-generated content and tracking it through system chains creates new integrity concerns. Each level compounds the challenges of the ones before it, ultimately manifesting in human costs, such as reinforced biases and diminished agency.

Think of it like protecting a house. You don’t just lock a door; you also use safe concrete foundations, sturdy framing, a durable roof, secure double-pane windows, and maybe motion-sensor cameras. Similarly, we need digital security at every layer to ensure the whole system can be trusted.

This layered approach to understanding security becomes increasingly critical as AI systems grow in complexity and autonomy, particularly with large language models (LLMs) and deep-learning systems making high-stakes decisions. We need to verify the integrity of each layer when building and deploying digital systems that impact human lives and societal outcomes.

At the foundation level, bits are stored in computer hardware. This represents the most basic encoding of our data, model weights, and computational instructions. The next layer up is the file system architecture: the way those binary sequences are organized into structured files and directories that a computer can efficiently access and process. In AI systems, this includes how we store and organize training data, model checkpoints, and hyperparameter configurations.

On top of that are the application layers—the programs and frameworks, such as PyTorch and TensorFlow, that allow us to train models, process data, and generate outputs. This layer handles the complex mathematics of neural networks, gradient descent, and other ML operations.

Finally, at the user-interface level, we have visualization and interaction systems—what humans actually see and engage with. For AI systems, this could be everything from confidence scores and prediction probabilities to generated text and images or autonomous robot movements.

Why does this layered perspective matter? Vulnerabilities and integrity issues can manifest at any level, so understanding these layers helps security experts and AI researchers perform comprehensive threat modeling. This enables the implementation of defense-in-depth strategies—from cryptographic verification of training data to robust model architectures to interpretable outputs. This multi-layered security approach becomes especially crucial as AI systems take on more autonomous decision-making roles in critical domains such as healthcare, finance, and public safety. We must ensure integrity and reliability at every level of the stack.

The risks of deploying AI without proper integrity control measures are severe and often underappreciated. When AI systems operate without sufficient security measures to handle corrupted or manipulated data, they can produce subtly flawed outputs that appear valid on the surface. The failures can cascade through interconnected systems, amplifying errors and biases. Without proper integrity controls, an AI system might train on polluted data, make decisions based on misleading assumptions, or have outputs altered without detection. The results of this can range from degraded performance to catastrophic failures.

We see four areas where integrity is paramount in this Web 3.0 world. The first is granular access, which allows users and organizations to maintain precise control over who can access and modify what information and for what purposes. The second is authentication—much more nuanced than the simple “Who are you?” authentication mechanisms of today—which ensures that data access is properly verified and authorized at every step. The third is transparent data ownership, which allows data owners to know when and how their data is used and creates an auditable trail of data providence. Finally, the fourth is access standardization: common interfaces and protocols that enable consistent data access while maintaining security.

Luckily, we’re not starting from scratch. There are open W3C protocols that address some of this: decentralized identifiers for verifiable digital identity, the verifiable credentials data model for expressing digital credentials, ActivityPub for decentralized social networking (that’s what Mastodon uses), Solid for distributed data storage and retrieval, and WebAuthn for strong authentication standards. By providing standardized ways to verify data provenance and maintain data integrity throughout its lifecycle, Web 3.0 creates the trusted environment that AI systems require to operate reliably. This architectural leap for integrity control in the hands of users helps ensure that data remains trustworthy from generation and collection through processing and storage.

Integrity is essential to trust, on both technical and human levels. Looking forward, integrity controls will fundamentally shape AI development by moving from optional features to core architectural requirements, much as SSL certificates evolved from a banking luxury to a baseline expectation for any Web service.

Web 3.0 protocols can build integrity controls into their foundation, creating a more reliable infrastructure for AI systems. Today, we take availability for granted; anything less than 100% uptime for critical websites is intolerable. In the future, we will need the same assurances for integrity. Success will require following practical guidelines for maintaining data integrity throughout the AI lifecycle—from data collection through model training and finally to deployment, use, and evolution. These guidelines will address not just technical controls but also governance structures and human oversight, similar to how privacy policies evolved from legal boilerplate into comprehensive frameworks for data stewardship. Common standards and protocols, developed through industry collaboration and regulatory frameworks, will ensure consistent integrity controls across different AI systems and applications.

Just as the HTTPS protocol created a foundation for trusted e-commerce, it’s time for new integrity-focused standards to enable the trusted AI services of tomorrow.

This essay was written with Davi Ottenheimer, and originally appeared in Communications of the ACM.

Validate Your Lambda Runtime with CloudFormation Lambda Hooks

Post Syndicated from Matteo Luigi Restelli original https://aws.amazon.com/blogs/devops/validate-your-lambda-runtime-with-cloudformation-lambda-hooks/

Introduction

This post demonstrates how to leverage AWS CloudFormation Lambda Hooks to enforce compliance rules at provisioning time, enabling you to evaluate and validate Lambda function configurations against custom policies before deployment. Often these policies impact the way a software should be built, restricting language versions and runtimes. A great example is applying those policies on AWS Lambda, a serverless compute service for running code without having to provision or manage servers. While AWS Lambda already manages the deprecation of runtimes, preventing you from deploying unsupported runtimes, organizations may need to provide and enforce their specific compliance rules not directly linked to the deprecation of a specific language version.

Introducing Lambda Hooks

AWS CloudFormation Lambda Hooks are a powerful feature that allows developers to evaluate CloudFormation and AWS Cloud Control API operations against custom code implemented as Lambda functions. This capability enables proactive inspection of resource configurations before provisioning, enhancing security, compliance, and operational efficiency.

Lambda Hooks provide a mechanism to intercept and evaluate various CloudFormation operations, including resource operations, stack operations, and change set operations (they can also be used with Cloud Control API, but in this post we’re focusing on CloudFormation). By activating a Lambda Hook, CloudFormation creates an entry in your account’s registry as a private Hook, allowing you to configure it for specific AWS accounts and regions. When configuring Lambda Hooks, you can specify one or more Lambda functions to be invoked during the evaluation process. These functions can be in the same AWS account and Region as the Hook, or in another Account you own, provided proper permissions are set up. The evaluation process occurs at specific points in the CloudFormation Stack lifecycle. For instance, during stack creation, update, or deletion, the configured Lambda functions are invoked to assess the proposed changes against your defined compliance rules. Based on the evaluation results, the hook can either block the operation or issue a warning, allowing the operation to proceed.

Lambda Hooks evaluate resources before they are provisioned through CloudFormation, providing a pre-emptive layer of governance. This means that non-compliant resources are caught and prevented from being deployed, rather than requiring retroactive fixes. By leveraging Lambda Hooks, organizations can automate and standardize their compliance checks across all AWS accounts and regions. This centralized approach to policy enforcement ensures consistency and reduces the overhead of managing compliance manually.

Solution Overview

The following sections demonstrate a practical use case for AWS CloudFormation Lambda Hooks, focusing on enforcing compliance rules on AWS Lambda runtimes.

Meet AnyCompany, a forward-thinking enterprise with a robust set of compliance rules governing their software development practices. Among these rules is a strict policy on the use of specific AWS Lambda runtimes.

As they continue to embrace serverless architecture, AnyCompany faces a challenge: how to prevent the deployment of Lambda functions that use non-compliant runtimes. Given their commitment to AWS CloudFormation for deploying Lambda functions, AnyCompany is keen to leverage the power of AWS CloudFormation Lambda Hooks.

We’ll explore the setup process, demonstrate the hook in action, and discuss the broader implications for maintaining compliance in a dynamic cloud environment.

Architecture

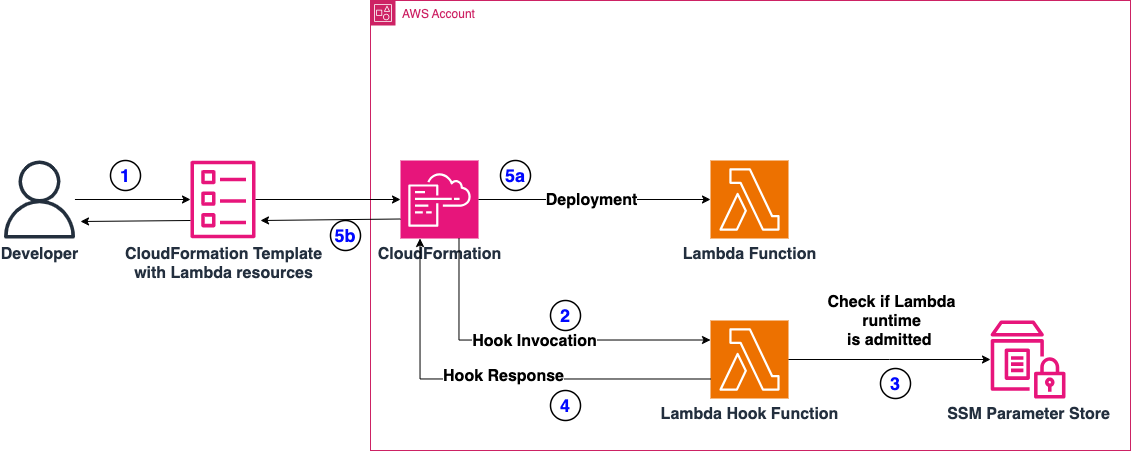
The following architecture highlights the implementation of the Lambda Hook. In this implementation, we are using AWS CloudFormation Lambda Hooks to intercept the deployment of Lambda Functions and perform the compliance checks on these resources. The Lambda Hook will interact with an AWS Lambda Function, which will perform the compliance checks. Finally, we’re using AWS Systems Manager Parameter Store to store the Configuration Parameter which contains the list of permitted Lambda Runtimes.

Figure 1: Architecture of the Solution

Figure 1: Architecture of the Solution

  1. A Developer (or a CI/CD pipeline) deploys a CloudFormation stack containing Lambda functions.
  2. CloudFormation invokes the respective Lambda Hook, which is configured to intercept operations on AWS Lambda Resources. We are setting this hook to “FAIL” deployment in case checks are not successful.
  3. The Lambda Hook checks if the runtime of the Lambda is admitted or violates Company’s compliance. To do this, it checks if the runtime is present on a pre-configured list of admitted runtimes saved as Parameter in AWS Systems Manager Parameter Store. Keep in mind that we’re using SSM Parameter Store to store the configuration for this specific example, but other alternatives may be viable as well (Amazon DynamoDB, AWS Secrets Manager, or AppConfig lambda-function-settings-check Preventive Rule)
  4. The Lambda Hook, after checking runtime compliance, replies:
    • With a failure, if the Lambda runtime is not compliant
    • With a success, if the Lambda runtime is compliant
  5. Depending on the response of the Lambda Hook, the deployment may or not take place.

Repository Structure

You can find all the code for this solution at this link. Here’s the repository structure:

.
├── README.md
├── deploy.sh
├── cleanup.sh
├── hook-lambda
│ ├── index.ts
│ ├── package.json
│ ├── services
│ │ └── parameter-store.ts
│ └── tsconfig.json
├── sample
│ ├── deploy_sample.sh
│ ├── cleanup_sample.sh
│ └── lambda_template.yml
└── template.yml
  • hook-lambda: directory containing all the code related to the CloudFormation Lambda Hook (Validation Lambda Function, and the CloudFormation template for the Solution)
  • sample: directory containing the code of the sample used to test the CloudFormation Lambda Hook
  • deploy.sh: utility script to deploy the Solution via AWS CLI
  • cleanup.sh: utility script to clean up the AWS CloudFormation Hook infrastructure via the AWS CLI
  • template.yml: AWS CloudFormation Template containing all the AWS Resources involved in the Solution

Prerequisites

You must have the following prerequisites for this solution:

  • An AWS account or sign up to create and activate one.
  • The following software installed on your development machine:
  • Install the AWS Command Line Interface (AWS CLI) and configure it to point to your AWS account.
  • Install Node.js and use a package manager such as npm.
  • Appropriate AWS credentials for interacting with resources in your AWS account.

Walkthrough

Creating the AWS Lambda Validation Function – Lambda Code

The CloudFormation Lambda Hook interacts with a specific Lambda (referred to as Validation Lambda throughout the rest of this post), which gets invoked during CloudFormation CREATE and UPDATE STACK operations involving Lambda Functions. The goal is to check if these Lambda functions have runtimes that comply with AnyCompany’s rules.

Below is the detailed description of the steps that the Validation Lambda function handler follows (the code is written in Typescript).

First, the Validation Lambda retrieves an environment variable containing the SSM Parameter Store parameter name which contains the compliant runtimes list. Additionally, safety checks ensure that only Lambda Resources are considered and that their Runtime property is defined.

Note that both safety checks could be skipped, since the Hook should already be configured to interact only with Lambda Resources and the Lambda’s Runtime property is always required. However, they remain in place to demonstrate how to retrieve this information from the Lambda Hook event in your handler.

const parameterName = process.env.PERMITTED_RUNTIMES_PARAM;
if (!parameterName) {
	throw new Error('Permitted Runtimes Parameter is not set');
}

const resourceProperties = event.requestData.targetModel.resourceProperties;
// Check if this is a Lambda function resource
if (event.requestData.targetType !== 'AWS::Lambda::Function') {
console.log("Resource is not a Lambda function, skipping");
	return {
		hookStatus: 'SUCCESS',
		message: 'Not a Lambda function resource, skipping validation',
		clientRequestToken: event.clientRequestToken
	}
}

// Check runtime version compliance
const runtime = resourceProperties.Runtime;
if (!runtime) {
	console.log("Runtime not defined, failing");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: 'Runtime is required for Lambda functions',
		clientRequestToken: event.clientRequestToken
	}
}

Then the Validation Lambda retrieves the value of the Configuration Parameter from SSM Parameter Store through a utility class called ParameterStoreService. For this post, consider that the value inside that Configuration Parameter is a list of strings, where each string contains one of the possible Lambda runtime values that you can find here (e.g. nodejs22.x,nodejs20.x,python3.11,python3.10,java17,java11,dotnet6). After retrieving the value, the Validation Lambda checks if the runtime of the Lambda Resource complies with the configured admitted runtimes. If the runtime is not compliant, you’ll receive a properly formatted response with FAILURE as hookStatus, otherwise the response will contain a SUCCESS hookStatus.

// Retrieve configuration from Parameter Store
const compliantRuntimes = await parameterStoreService.getParameterFromStore(parameterName);

// Check if Lambda runtime is permitted or not
if (!compliantRuntimes.includes(runtime)) {
console.log("Runtime " + runtime + " not compliant ");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: `Runtime ${runtime} is not compliant. Please use one of: ${compliantRuntimes.join(', ')}`,
		clientRequestToken: event.clientRequestToken
	}
}

return {
	hookStatus: 'SUCCESS',
	message: 'Runtime version compliance check passed',
	clientRequestToken: event.clientRequestToken
}

For more information about the possible response values of CloudFormation Lambda Hooks Lambda, have a look at this link.

Creating the validation Lambda – Lambda CloudFormation definition

The Validation Lambda function will be deployed via CloudFormation, in the same Stack with the CloudFormation Lambda Hook definition and the AWS Systems Manager Parameter Store Parameter. Here’s the fragment of the CloudFormation Template containing its definition:

# Lambda Function
ValidationFunction:
	Type: AWS::Lambda::Function
	Properties:
		Handler: index.handler
		Role: !GetAtt LambdaExecutionRole.Arn
		Code:
			S3Bucket: !Ref DeploymentBucket
			S3Key: hook-lambda.zip
		Runtime: nodejs22.x
		Timeout: 60
		MemorySize: 128
		Environment:
			Variables:
				PERMITTED_RUNTIMES_PARAM: !Ref ParameterStoreParamName

You’ll need to associate an IAM Role with proper permissions to access the AWS Systems Manager Parameter Store Parameter:

# Lambda Function Role
LambdaExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: lambda.amazonaws.com
            Action: sts:AssumeRole
      ManagedPolicyArns:
        - arn:aws:iam::aws:policy/service-role/AWSLambdaBasicExecutionRole
		
# IAM Policy to access Parameter Store
ParameterStoreAccessPolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref LambdaExecutionRole
      PolicyName: ParameterStoreAccess
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - ssm:GetParameter
            Resource: !Sub arn:aws:ssm:${AWS::Region}:${AWS::AccountId}:parameter${ParameterStoreParamName}

Creating the CloudFormation Lambda Hook

At this point, you only need to author a proper CloudFormation Lambda Hook. The Hook requires:

  • To be activated during the CREATE and UPDATE CloudFormation operations,
  • To consider only AWS::Lambda::Function CloudFormation resources
  • To act during Pre Provisioning of CloudFormation templates
  • To target Stack and Resource Operations
  • Target the already defined Lambda Validation function

Here’s the definition in the CloudFormation template:

# Lambda Hook
ValidationHook:
    Type: AWS::CloudFormation::LambdaHook
    Properties:
      Alias: Private::Lambda::LambdaResourcesComplianceValidationHook
      LambdaFunction: !GetAtt ValidationFunction.Arn
      ExecutionRole: !GetAtt HookExecutionRole.Arn
      FailureMode: FAIL
      HookStatus: ENABLED
      TargetFilters:
        Actions:
          - CREATE
          - UPDATE
        InvocationPoints:
          - PRE_PROVISION
        TargetNames:
          - AWS::Lambda::Function
      TargetOperations:
        - RESOURCE
        - STACK

Please note that the above template contains a reference to an IAM Role because the Hook requires proper permissions to call the target (Lambda Function). Here’s the IAM Role definition:

# Hook Execution Role
HookExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: hooks.cloudformation.amazonaws.com
            Action: sts:AssumeRole

# IAM Policy for Lambda Invocation
LambdaInvokePolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref HookExecutionRole
      PolicyName: LambdaInvokePolicy
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - lambda:InvokeFunction
            Resource: !GetAtt ValidationFunction.Arn

Configuring the compliant runtimes – Using Systems Manager Parameter Store

AWS Systems Manager Parameter Store is a secure, hierarchical storage service for configuration data management and secrets management, allowing users to store and retrieve data such as configurations, database strings etc. as parameter values.

In this specific example, we’ll leverage Parameter Store to store our permitted Lambda runtimes configuration. This configuration value is a StringList parameter, containing a comma-separated list of permitted runtimes. Here’s the fragment of the CloudFormation template that defines the Parameter:

# Parameter Store Parameter
ConfigParameter:
    Type: AWS::SSM::Parameter
    Properties:
      Name: !Ref ParameterStoreParamName
      Type: StringList
      Value: !Ref ParameterStoreDefaultValue
      Description: "Configuration for Lambda Hook"

Please note the usage of CloudFormation parameters for the ‘Name’ and ‘Value’ properties, allowing for dynamic input when deploying the CloudFormation template.

Deploying the Solution

To deploy the solution you can leverage the script deploy.sh in the root folder of the repository. This script will perform the following actions:

  • Compile and build the Validation Lambda Function
  • Create an Amazon S3 Bucket to store the CloudFormation Template
  • Upload the CloudFormation template and Lambda code to the S3 Bucket
  • Deploy the CloudFormation template

Testing the Lambda Hook

To test the CloudFormation Lambda Hook, deploy a simple testing CloudFormation template containing a Hello World Lambda function. First, test the Lambda configured with a permitted Lambda runtime, then modify the template to configure the Lambda with a non-compliant runtime.

Here’s the initial definition of the testing CloudFormation Template:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs22.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

Please note that the Runtime value is nodejs22.x, which is currently in the list of permitted runtimes. The expectation is that the deployment of this function will succeed.

Deploy this template via the AWS CLI:

aws cloudformation deploy \
--template-file ./lambda_template.yml \
--capabilities CAPABILITY_IAM \
--stack-name lambda-sample

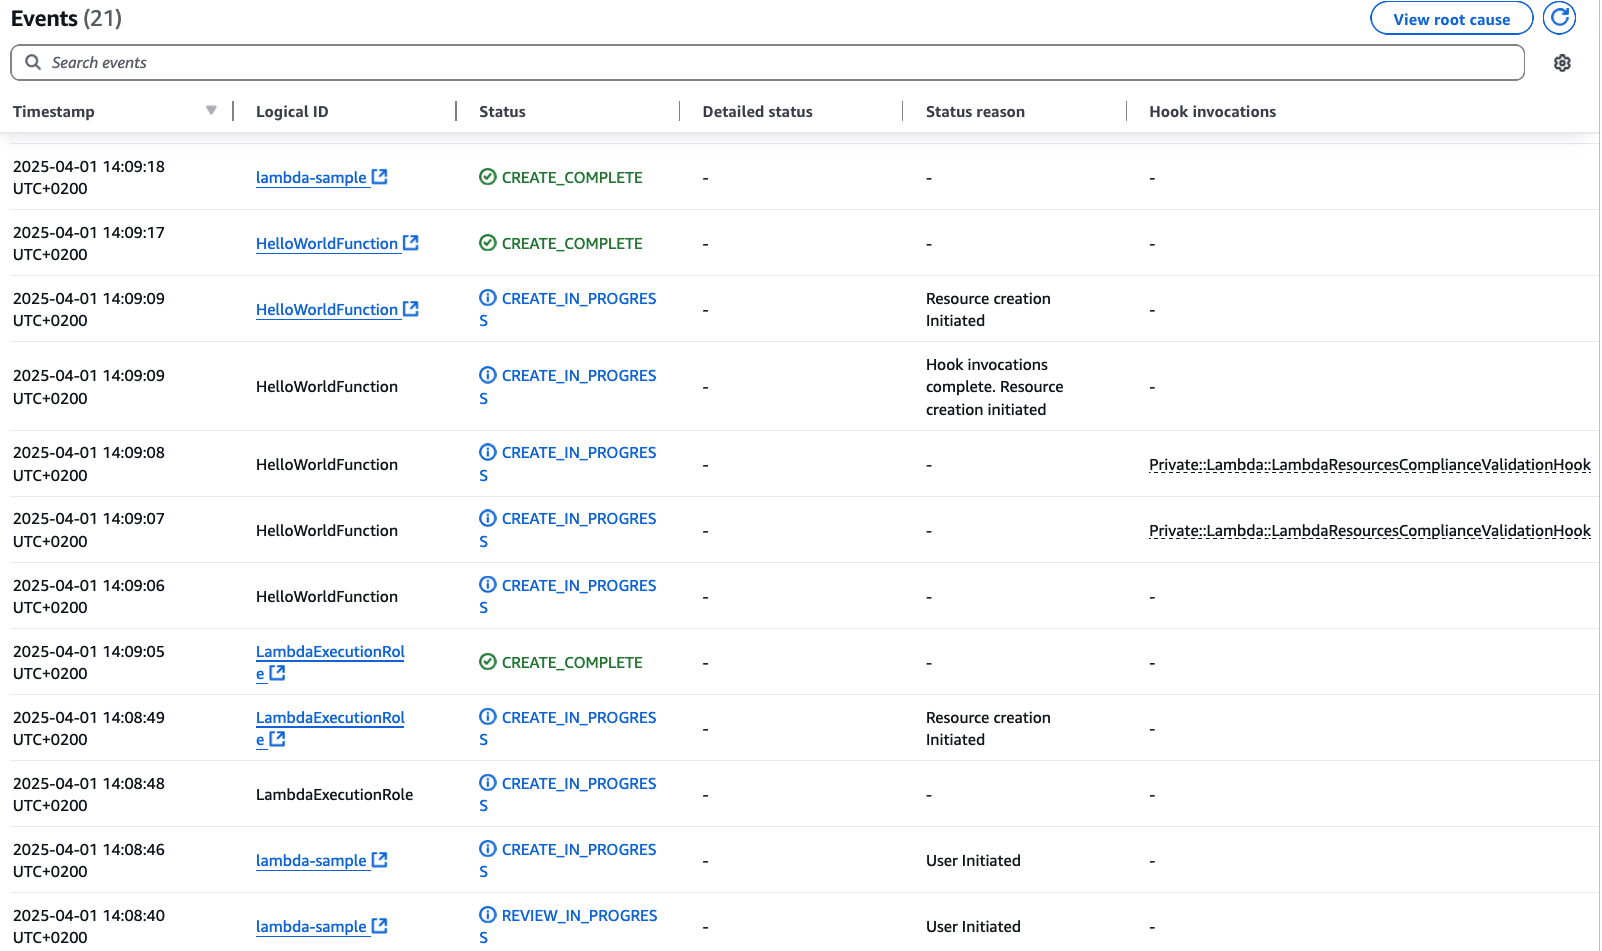
Check the CloudFormation Console:

CloudFormation Console showing successful Stack deployment

Figure 2: CloudFormation Console showing successful Stack deployment

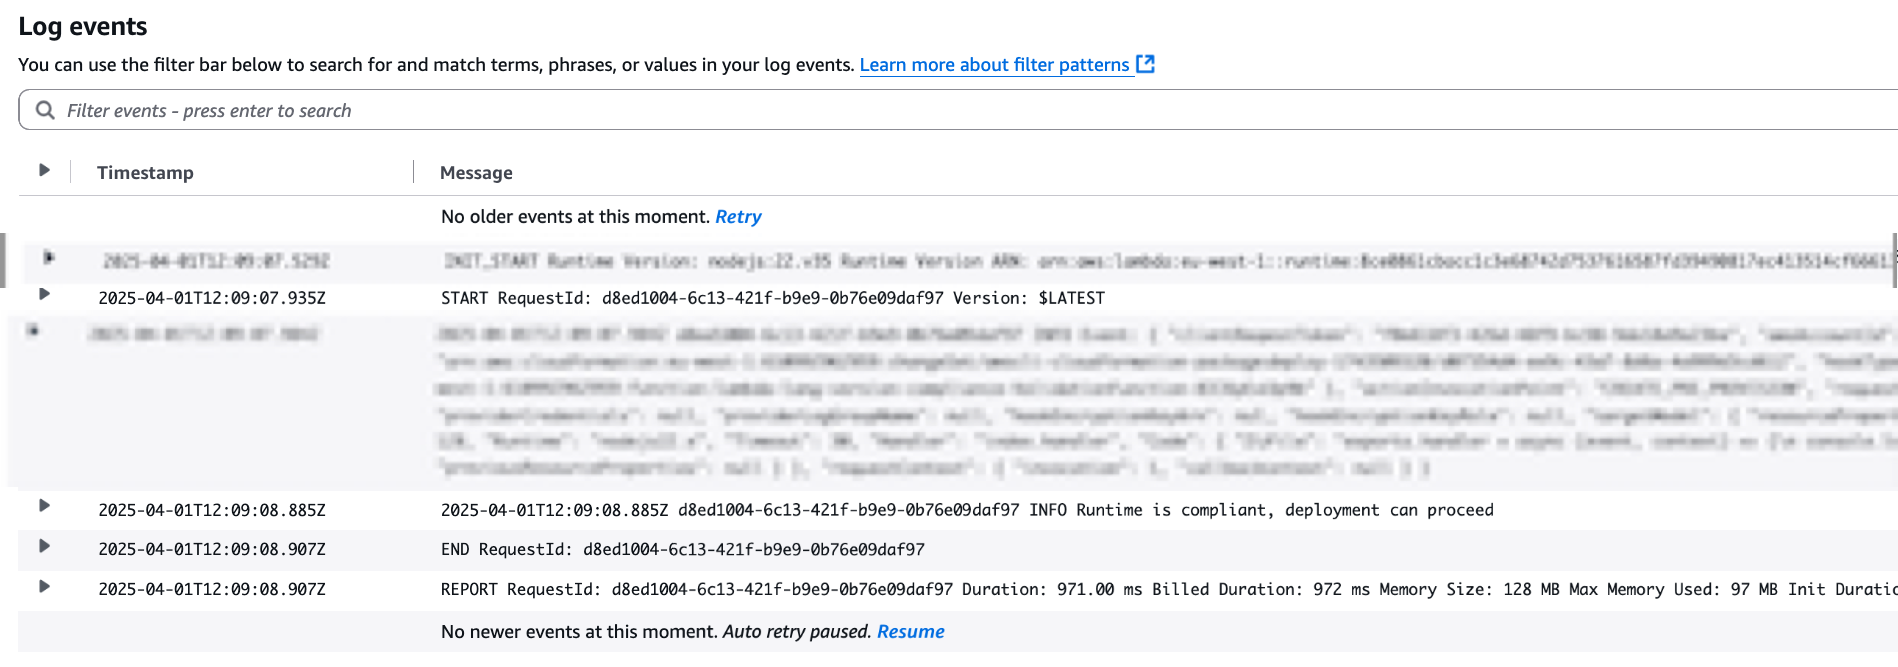
As expected, the deployment was successful. You can also see that the CloudFormation Lambda Hook has been invoked by taking a look at the CloudWatch Logs:

Validation Lambda Function Logs with successful validation

Figure 3: Validation Lambda Function Logs with successful validation

Now modify the original sample Template in order to set a Lambda Runtime which is not inside the list of permitted runtimes:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs18.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

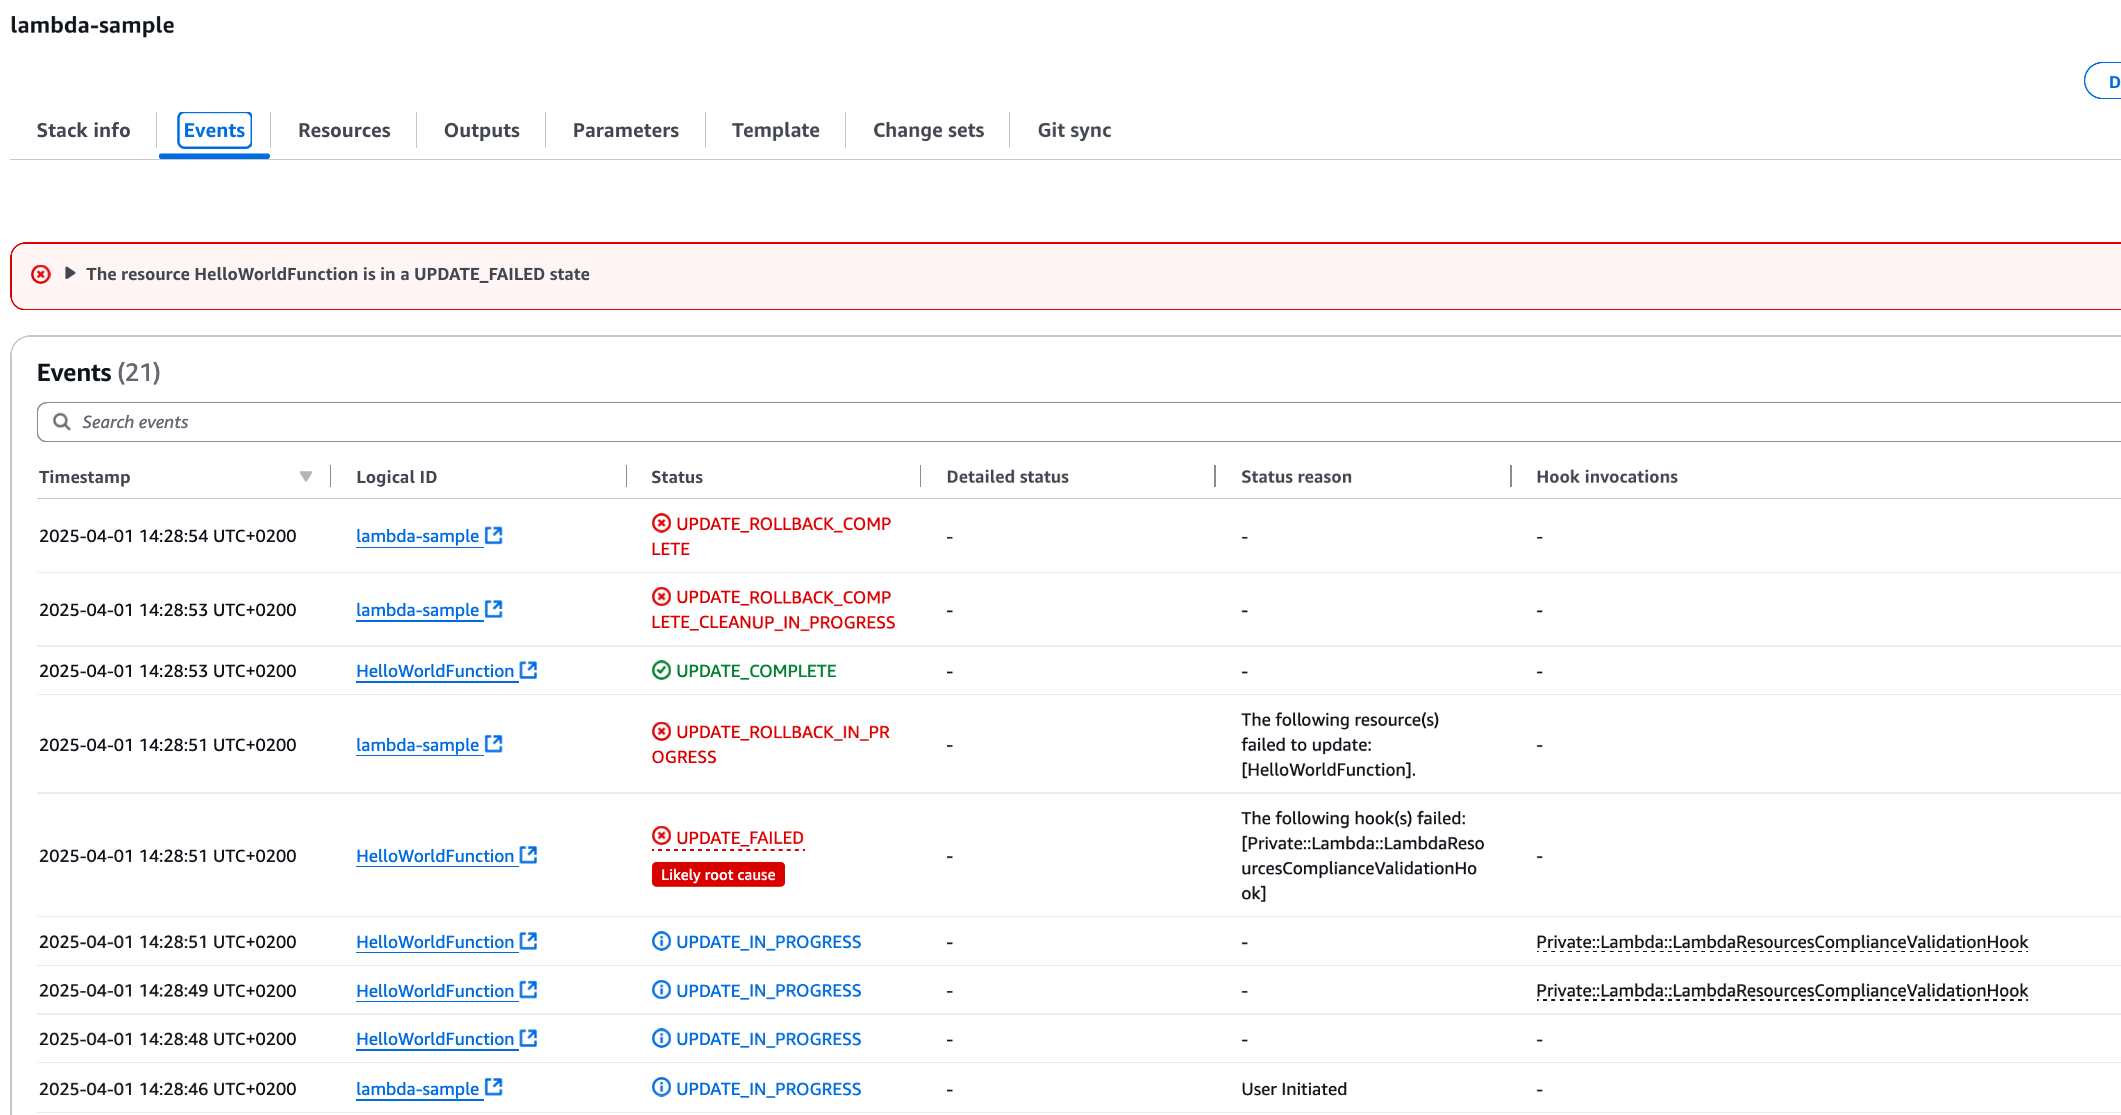
Deploy this template via AWS CLI with the same command used before and check the CloudFormation Console:

CloudFormation Console showing failed Stack deployment due to Hook intervention

Figure 4: CloudFormation Console showing failed Stack deployment due to Hook intervention

As expected, the deployment was not successful. The CloudFormation Lambda Hook has been invoked, and since the Lambda Runtime was not present in the permitted runtimes list, the deployment failed.

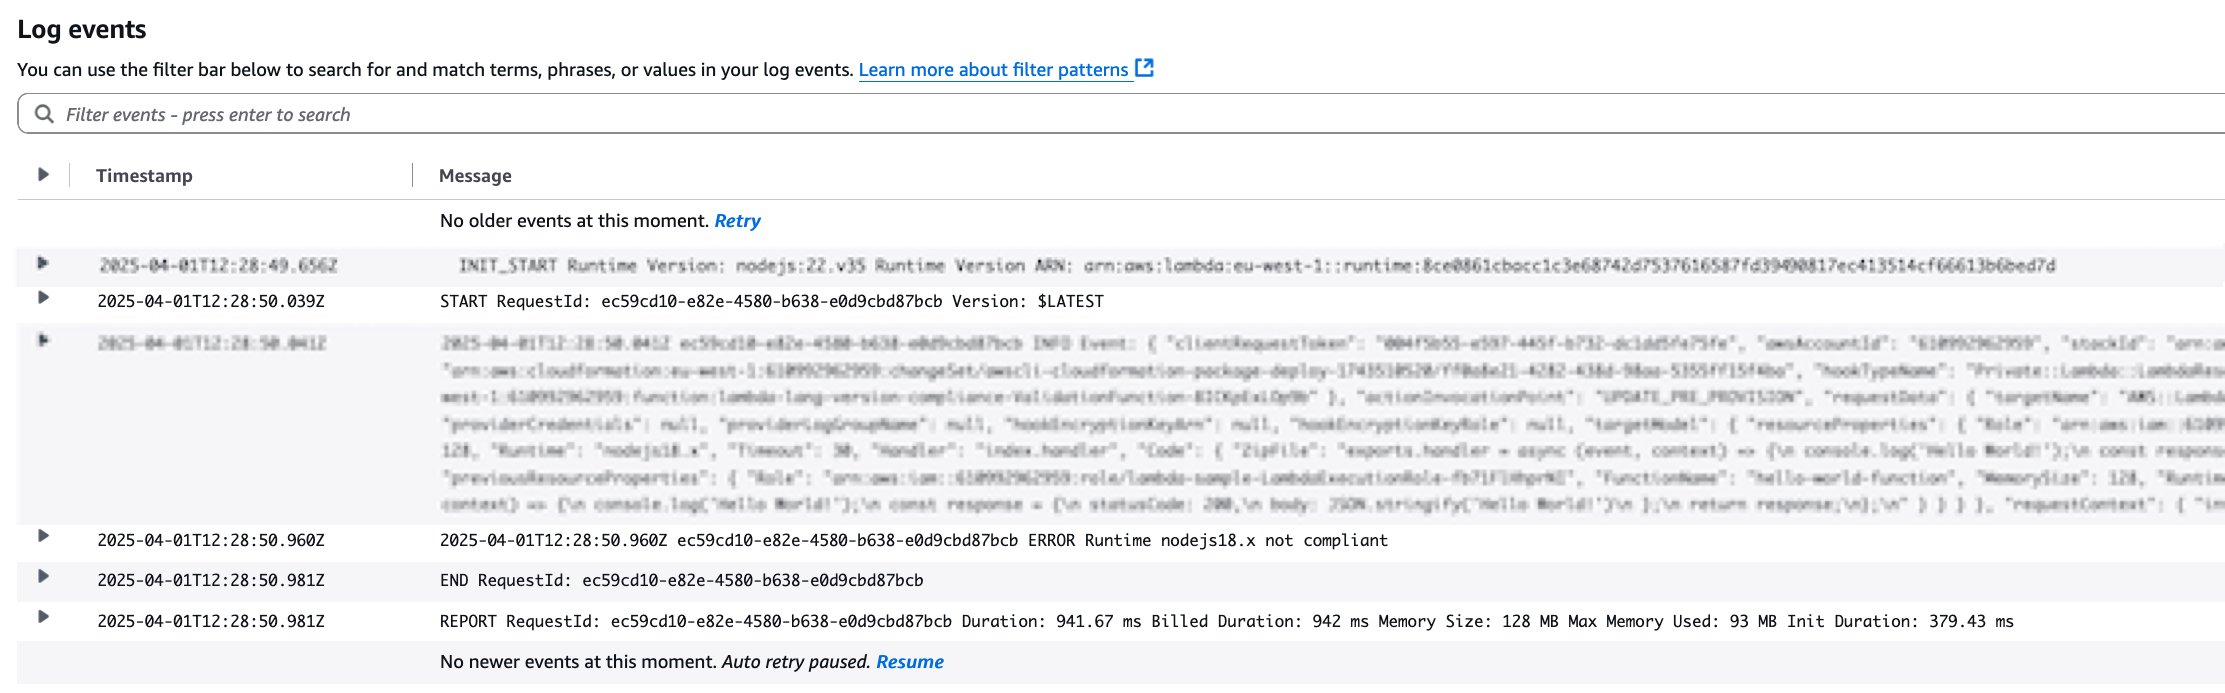
You can also see that the hook failed In the CloudWatch Logs:

Validation Lambda Function Logs with validation error

Figure 5: Validation Lambda Function Logs with validation error

Cleaning up

To clean up the resources related to the sample, you can run the script cleanup_sample.sh inside the sample folder. This script will delete the sample’s CloudFormation Template through the AWS CLI.

To cleanup the resources related to the solution described above and based on AWS CloudFormation Lambda Hook, you can leverage the script cleanup.sh in the root folder of the repository. This script will perform the following actions:

  • Delete the CloudFormation Stack
  • Empty the S3 Bucket used for the deployment of the Stack
  • Delete the S3 Bucket

Conclusion

In this post, you explored the implementation of CloudFormation Hooks to enforce runtime compliance in Lambda functions across your AWS infrastructure. By leveraging the Lambda hook’s capabilities, you learned how to create a preventative control that validates Lambda runtime configurations before deployment.

By activating the Lambda hook and implementing a custom Lambda function validator, you established an automated mechanism to ensure that only compliant runtimes are used within your organization’s Lambda functions during CloudFormation stack creation and updates. The solution’s integration with common development tools like AWS CLI, AWS SAM, CI/CD pipelines, and AWS CDK makes it straightforward to implement these controls within existing workflows, eliminating the need for manual runtime checks or post-deployment remediation.

The validation approach demonstrated in this post extends beyond Lambda runtimes and can be adapted to different AWS Resources supported by CloudFormation, allowing you to enforce policies on different infrastructure components offered by AWS.

About the author

Matteo Luigi Restelli

Matteo Luigi Restelli is an AWS Sr. Partner Solutions Architect. He mainly focuses on Italian Consulting AWS Partners and is also specialized in Infrastructure as Code, Cloud Native App Development and DevOps. Outside of work, he enjoys swimming, rock & roll music and learning something new everyday especially in Computer Science space.

Stella Hie

Stella Hie is a Sr. Product Manager Technical for AWS Infrastructure as Code. She focuses on proactive control and governance space, working on delivering the best experience for customers to use AWS solutions safely. Outside of work, she enjoys hiking, playing piano, and watching live shows.

Rational Astrologies and Security

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/rational-astrologies-and-security.html

John Kelsey and I wrote a short paper for the Rossfest Festschrift: “Rational Astrologies and Security“:

There is another non-security way that designers can spend their security budget: on making their own lives easier. Many of these fall into the category of what has been called rational astrology. First identified by Randy Steve Waldman [Wal12], the term refers to something people treat as though it works, generally for social or institutional reasons, even when there’s little evidence that it works—­and sometimes despite substantial evidence that it does not.

[…]

Both security theater and rational astrologies may seem irrational, but they are rational from the perspective of the people making the decisions about security. Security theater is often driven by information asymmetry: people who don’t understand security can be reassured with cosmetic or psychological measures, and sometimes that reassurance is important. It can be better understood by considering the many non-security purposes of a security system. A monitoring bracelet system that pairs new mothers and their babies may be security theater, considering the incredibly rare instances of baby snatching from hospitals. But it makes sense as a security system designed to alleviate fears of new mothers [Sch07].

Rational astrologies in security result from two considerations. The first is the principal­-agent problem: The incentives of the individual or organization making the security decision are not always aligned with the incentives of the users of that system. The user’s well-being may not weigh as heavily on the developer’s mind as the difficulty of convincing his boss to take a chance by ignoring an outdated security rule or trying some new technology.

The second consideration that can lead to a rational astrology is where there is a social or institutional need for a solution to a problem for which there is actually not a particularly good solution. The organization needs to reassure regulators, customers, or perhaps even a judge and jury that “they did all that could be done” to avoid some problem—even if “all that could be done” wasn’t very much.

Cell Phone OPSEC for Border Crossings

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/cell-phone-opsec-for-border-crossings.html

I have heard stories of more aggressive interrogation of electronic devices at US border crossings. I know a lot about securing computers, but very little about securing phones.

Are there easy ways to delete data—files, photos, etc.—on phones so it can’t be recovered? Does resetting a phone to factory defaults erase data, or is it still recoverable? That is, does the reset erase the old encryption key, or just sever the password that access that key? When the phone is rebooted, are deleted files still available?

We need answers for both iPhones and Android phones. And it’s not just the US; the world is going to become a more dangerous place to oppose state power.

Adopting Amazon Q Developer in Enterprise Environments

Post Syndicated from Rene-Martin Tudyka original https://aws.amazon.com/blogs/devops/adopting-amazon-q-developer-in-enterprise-environments/

Increasing developer productivity has been a persistent challenge for senior leaders over the past decades. With the rise of generative artificial intelligence (AI), a new wave of innovation is transforming how software teams work. Generative AI tools like Amazon Q Developer are emerging as game-changers, supporting developers across the entire software development lifecycle. But how are large-scale organizations successfully adopting this AI-assisted approach? This document shares good practices I have discovered through working with enterprise customers navigating this technological transformation.

A common misperception still is that a developer is more productive when they write code faster. But a median developer spends less than one hour per day writing code, as a study conducted by software.com in 2022 shows. This makes clear that there are other aspects to consider when it comes to building an application and running it in production. Generative AI tools for developers, such as Amazon Q Developer, started as coding companions that provided inline completions. As the technology evolved, Amazon Q Developer is now able to support developers across the entire software development life cycle.

The Change Challenge

Generative AI offers new and interesting ways for developers to solve challenges and to support them in their daily work. But taking advantage of those opportunities takes some time. It introduces a noticeable change to their familiar ways of working and therefore it is much about forming a new habit. This, according to science, usually takes a minimum of two months. Teams need the space and permission to play with this new approach and to find out what works best for them. Expecting them to adopt a new way of working while expecting the same (or higher) level of output at the same time will only lead to teams falling back to what they know works. For customers that successfully have adopted Amazon Q Developer I have seen them reducing the delivery expectations to give space to learn, and having required teams to share learnings in return.

Additionally, as in any other large change project there is a significant cultural aspect to consider. If people feel intrinsically convinced by the value and benefits of an AI-supported approach to software engineering they will use it. “Simply ordering from above” will not help making an adoption successful. But building community, experimenting, learning, and sharing successes will. “Culture eats strategy for breakfast”, as the management visionary Peter Drucker said.

Keeping that in mind it is clear that there is no one-size-fits-all prescriptive way of successfully introducing generative AI tools for developers in your organization. It very much depends on your individual culture, goals, challenges, people, skills, and technology stack for example. However, there are a number of principles and good practices that work well with several of our large-scale customers who have successfully adopted Amazon Q Developer.

Best Practices for Successful Adoption

The following illustration describes the change management cycle and recommended activities for adopting AI-assisted software development.

The change management cycle – align, plan, roll out, reflect and repeat

Figure 1. The change management cycle

1. Secure Top-Down Commitment

Secure executive buy-in for adopting AI-assisted software development because this is a powerful sign for the organization. It helps to remove roadblocks and to promote successes across the organization. An executive sponsor links the adoption of AI-assisted software development to the strategic goals of the organization, will help resolving prioritization and capacity conflicts. Invite the sponsor to a kick-off meeting. Include them for the discussion of goals and success criteria, and keep them updated on progress, success stories, and challenges.

2. Become Clear on Goals and Success Criteria

Simply rolling out Generative AI tools to a large developer base won’t be enough. You need to be clear what you expect from such an adoption for your organization, for your developers, and for your business. It is important for you to understand your organization’s pain points from a developer experience perspective and how they affect your development productivity. These likely differ between different personas, like Software Developers and DevOps Engineers. For example, are your applications lacking test coverage or is your code lacking documentation, which creates a maintenance burden, and makes it difficult to onboard new developers? Is handling legacy code risky and time-consuming so that you avoid necessary upgrades because of the complexity and effort? Is troubleshooting applications locally or in production eating up your developers’ time? Or are you facing challenges caused by hard-to-find security issues in the code? What is it that you want to achieve by introducing an AI-assisted development approach, and why?

3. Establish Ownership

Adopting a new approach like the use of generative AI in software development at scale leads to many change management and coordination tasks. Those are related to getting access to the tool, enablement for new users, budget planning, measuring success and creating transparency on problems, creating momentum and making sure the adoption sustains, amongst others. Therefore, introducing a Customer Champion as a leader who coordinates the business and technology related aspects of the adoption is a common approach. They will connect the strategic goals of the organization with the tactical activities necessary for the implementation. If your adoption is spanning multiple different business units with larger developer bases consider establishing this role for each of them, forming a team that collaborates across your whole organization. Key responsibilities of the Customer Champion are to bring the right people together to successfully work on the adoption, to create transparency on status, and to address impediments early on.

4. Introduce Metrics

Once you have gained clarity on the specific pain points and goals for your organization, the next step is to determine the appropriate metrics to measure the success of your efforts. For example, you can measure the impact of using Amazon Q Developer on onboarding new developers by tracking the time to first commit against a previously established baseline average. Comparing the time it takes to complete certain tasks – like writing and integrating code, fixing bugs, setting up or upgrading environments, the time it takes to build a new feature, or by comparing sprint velocity before and after the introduction of Amazon Q Developer will give you further indications. But keep in mind that there is ambiguity in these metrics because they are impacted by different factors.

Focusing on developer experience and productivity, monitor the development of your established measurement framework, like DORA, SPACE, or GSM. SPACE in particular, with its “Satisfaction & Well-Being” dimension, pays close attention to how software developers perceive their work and how satisfied they are with their own productivity. Tools like Amazon Q Developer have shown a positive effect here, as for example a McKinsey study shows. They help to free developers from tasks that are perceived as toil, like repetitive and boring grunt work that doesn’t necessarily bring business value. To measure this impact on perceived productivity, customers sometimes design simple surveys, asking developers questions like “in percentage, how would you estimate the impact of using Amazon Q Developer on your productivity” or “on a scale from 1-5, how is Amazon Q Developer impacting the satisfaction with your day-to-day work?”

As a last dimension, understanding the general usage of Amazon Q Developer across your organization is important. Monitor the number active subscriptions, accepted code recommendations, or the number of executed security scans from the Amazon Q Developer dashboard. That way you will get an understanding for the acceptance of the tool in your developer base. Correlate this information with the success metrics you defined.

5. Start Small

When “rolling out” an AI-assisted software development approach, keep the technology adoption lifecycle and Everett Roger’s bell curve in mind. It describes that adoption of a new technology usually starts with a few “innovators”, followed by a small fraction of “early adopters”. Only if those early groups demonstrate convincing success, the majority of users will follow the adoption. To settle on this model will help you making the adoption of AI-assisted development successful in your organization.

Start small. Identify your tech innovators, or champions, who are enthusiastic to support the introduction of Amazon Q Developer and to advocate the approach in your organization. With them, build a team or a Center of Excellence (COE) that will help with identifying early adopters across your development teams, building technical and enablement foundations for onboarding users, creating roll-out plans, and evangelizing and sustaining the adoption. The champions will act as a bridge between your adoption program team and your users. They can provide insights and feedback on the adoption and come up with recommendations.

6. Create Momentum

Now that you have your foundations in place it is time to create momentum and onboard your early adopters to Amazon Q Developer. Start with a communication plan to raise awareness, to share updates and success stories, and to collect feedback from the users. You will need to create training material covering organization-specific resources (how to get access, for example, or which communication channels and contact points exist), user guides, tutorials, and pointers to relevant documentation and online resources. Consider creating your own prompt library, documenting prompts for Amazon Q Developer that your users find particularly helpful. There are community projects like promptz.dev that can deliver inspiration. Especially for new users this will have a lot of value for getting up to speed.

Consider how to integrate learning pathways with your organization’s learning platform moving forward. These should include the company-specific experience and knowledge you collect. In addition, it might be helpful to integrate external offers, like classroom trainings or workshop formats offered by AWS.

Hands-on technical enablement workshops will help your early adopters jumpstarting their experience. AWS offers multiple formats that can be tailored to your individual context. These include service deep-dives with Amazon Q Developer specialists, Immersion Days and hackathon support for teams to hands-on experience the tool in a guided, interactive format, or joined proof-of-value engagements. Your AWS account team will provide you more information.

7. Sustain and Scale Adoption

At that point you will have established Amazon Q Developer among an initial segment of your developer base. However, keeping Roger’s adoption curve in mind the largest part of the adoption still lies ahead of you. To facilitate the it across your whole organization, focus on delivering enablement workshops for the teams to be onboarded. These will be led by your champions and incorporate your organization-specific practices and knowledge.

To sustain the adoption, make sure the existing user base stays active. Continue offering exchange and support, collecting feedback, updating your enablement material, sharing updates on the latest developments for Amazon Q Developer, and reviewing your metrics. Create visibility across your organization for the accomplishments and positive experiences. Let user talk about the impact Amazon Q Developer has on their work. This will help building momentum. Nurture community building around your users of AI-assisted development.

Establish regular office hours with your champions for providing support and enablement to your users of Amazon Q Developer. This will facilitate the continuous gathering of feedback to improve documentation and enablement materials, collect and promote success stories, and validate the adoption approach. Additionally, establish a consistent communications and reporting cadence to keep all relevant stakeholders informed of key metrics, updates, feedback, and success stories. This ensures the alignment of the adoption of AI-assisted development with your strategic goals and expectations.

8. Inspect and Adapt

In addition, keep reflecting on the goals and metrics you came up with from a strategic perspective. Are they developing in the right direction? Are your pain points still the same? Should you move your focus to different aspects of the software development life cycle? And how might new capabilities of Amazon Q Developer support your goals?

Conclusion

By following the outlined approach, large organizations can successfully navigate the challenges of adopting Amazon Q Developer. The approach addresses technical, cultural, and organizational aspects of the adoption, increasing the likelihood of realizing the full potential of AI-assisted development across the enterprise.

If you are looking for advice or support during your adoption journey, your AWS Account Team will connect you with experts on Amazon Q Developer, provide you information on training and enablement, and support you with setting up a successful rollout program for your organization. To learn more about how Amazon Q Developer’s capabilities support the whole software development lifecycle, visit the product page or have a look at the documentation.

About the Author

Rene-Martin Tudyka is a Senior Customer Solutions Manager at AWS and provides guidance and support for enterprise customers on their cloud maturity journey. He has a long background in developing highly performant IT organizations and in successful large-scale cloud adoption.

The Signal Chat Leak and the NSA

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/the-signal-chat-leak-and-the-nsa.html

US National Security Advisor Mike Waltz, who started the now-infamous group chat coordinating a US attack against the Yemen-based Houthis on March 15, is seemingly now suggesting that the secure messaging service Signal has security vulnerabilities.

"I didn’t see this loser in the group," Waltz told Fox News about Atlantic editor in chief Jeffrey Goldberg, whom Waltz invited to the chat. "Whether he did it deliberately or it happened in some other technical mean, is something we’re trying to figure out."

Waltz’s implication that Goldberg may have hacked his way in was followed by a report from CBS News that the US National Security Agency (NSA) had sent out a bulletin to its employees last month warning them about a security "vulnerability" identified in Signal.

The truth, however, is much more interesting. If Signal has vulnerabilities, then China, Russia, and other US adversaries suddenly have a new incentive to discover them. At the same time, the NSA urgently needs to find and fix any vulnerabilities quickly as it can—and similarly, ensure that commercial smartphones are free of backdoors—access points that allow people other than a smartphone’s user to bypass the usual security authentication methods to access the device’s contents.

That is essential for anyone who wants to keep their communications private, which should be all of us.

It’s common knowledge that the NSA’s mission is breaking into and eavesdropping on other countries’ networks. (During President George W. Bush’s administration, the NSA conducted warrantless taps into domestic communications as well—surveillance that several district courts ruled to be illegal before those decisions were later overturned by appeals courts. To this day, many legal experts maintain that the program violated federal privacy protections.) But the organization has a secondary, complementary responsibility: to protect US communications from others who want to spy on them. That is to say: While one part of the NSA is listening into foreign communications, another part is stopping foreigners from doing the same to Americans.

Those missions never contradicted during the Cold War, when allied and enemy communications were wholly separate. Today, though, everyone uses the same computers, the same software, and the same networks. That creates a tension.

When the NSA discovers a technological vulnerability in a service such as Signal (or buys one on the thriving clandestine vulnerability market), does it exploit it in secret, or reveal it so that it can be fixed? Since at least 2014, a US government interagency "equities" process has been used to decide whether it is in the national interest to take advantage of a particular security flaw, or to fix it. The trade-offs are often complicated and hard.

Waltz—along with Vice President J.D. Vance, Defense Secretary Pete Hegseth, and the other officials in the Signal group—have just made the trade-offs much tougher to resolve. Signal is both widely available and widely used. Smaller governments that can’t afford their own military-grade encryption use it. Journalists, human rights workers, persecuted minorities, dissidents, corporate executives, and criminals around the world use it. Many of these populations are of great interest to the NSA.

At the same time, as we have now discovered, the app is being used for operational US military traffic. So, what does the NSA do if it finds a security flaw in Signal?

Previously, it might have preferred to keep the flaw quiet and use it to listen to adversaries. Now, if the agency does that, it risks someone else finding the same vulnerability and using it against the US government. And if it was later disclosed that the NSA could have fixed the problem and didn’t, then the results might be catastrophic for the agency.

Smartphones present a similar trade-off. The biggest risk of eavesdropping on a Signal conversation comes from the individual phones that the app is running on. While it’s largely unclear whether the US officials involved had downloaded the app onto personal or government-issued phones—although Witkoff suggested on X that the program was on his "personal devices"—smartphones are consumer devices, not at all suitable for classified US government conversations. An entire industry of spyware companies sells capabilities to remotely hack smartphones for any country willing to pay. More capable countries have more sophisticated operations. Just last year, attacks that were later attributed to China attempted to access both President Donald Trump and Vance’s smartphones. Previously, the FBI—as well as law enforcement agencies in other countries—have pressured both Apple and Google to add "backdoors" in their phones to more easily facilitate court-authorized eavesdropping.

These backdoors would create, of course, another vulnerability to be exploited. A separate attack from China last year accessed a similar capability built into US telecommunications networks.

The vulnerabilities equities have swung against weakened smartphone security and toward protecting the devices that senior government officials now use to discuss military secrets. That also means that they have swung against the US government hoarding Signal vulnerabilities—and toward full disclosure.

This is plausibly good news for Americans who want to talk among themselves without having anyone, government or otherwise, listen in. We don’t know what pressure the Trump administration is using to make intelligence services fall into line, but it isn’t crazy to worry that the NSA might again start monitoring domestic communications.

Because of the Signal chat leak, it’s less likely that they’ll use vulnerabilities in Signal to do that. Equally, bad actors such as drug cartels may also feel safer using Signal. Their security against the US government lies in the fact that the US government shares their vulnerabilities. No one wants their secrets exposed.

I have long advocated for a "defense dominant" cybersecurity strategy. As long as smartphones are in the pocket of every government official, police officer, judge, CEO, and nuclear power plant operator—and now that they are being used for what the White House now calls calls  "sensitive," if not outright classified conversations among cabinet members—we need them to be as secure as possible. And that means no government-mandated backdoors.

We may find out more about how officials—including the vice president of the United States—came to be using Signal on what seem to be consumer-grade smartphones, in a apparent breach of the laws on government records. It’s unlikely that they really thought through the consequences of their actions.

Nonetheless, those consequences are real. Other governments, possibly including US allies, will now have much more incentive to break Signal’s security than they did in the past, and more incentive to hack US government smartphones than they did before March 24.

For just the same reason, the US government has urgent incentives to protect them.

This essay was originally published in Foreign Policy.

AIs as Trusted Third Parties

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/ais-as-trusted-third-parties.html

This is a truly fascinating paper: “Trusted Machine Learning Models Unlock Private Inference for Problems Currently Infeasible with Cryptography.” The basic idea is that AIs can act as trusted third parties:

Abstract: We often interact with untrusted parties. Prioritization of privacy can limit the effectiveness of these interactions, as achieving certain goals necessitates sharing private data. Traditionally, addressing this challenge has involved either seeking trusted intermediaries or constructing cryptographic protocols that restrict how much data is revealed, such as multi-party computations or zero-knowledge proofs. While significant advances have been made in scaling cryptographic approaches, they remain limited in terms of the size and complexity of applications they can be used for. In this paper, we argue that capable machine learning models can fulfill the role of a trusted third party, thus enabling secure computations for applications that were previously infeasible. In particular, we describe Trusted Capable Model Environments (TCMEs) as an alternative approach for scaling secure computation, where capable machine learning model(s) interact under input/output constraints, with explicit information flow control and explicit statelessness. This approach aims to achieve a balance between privacy and computational efficiency, enabling private inference where classical cryptographic solutions are currently infeasible. We describe a number of use cases that are enabled by TCME, and show that even some simple classic cryptographic problems can already be solved with TCME. Finally, we outline current limitations and discuss the path forward in implementing them.

When I was writing Applied Cryptography way back in 1993, I talked about human trusted third parties (TTPs). This research postulates that someday AIs could fulfill the role of a human TTP, with added benefits like (1) being able to audit their processing, and (2) being able to delete it and erase their knowledge when their work is done. And the possibilities are vast.

Here’s a TTP problem. Alice and Bob want to know whose income is greater, but don’t want to reveal their income to the other. (Assume that both Alice and Bob want the true answer, so neither has an incentive to lie.) A human TTP can solve that easily: Alice and Bob whisper their income to the TTP, who announces the answer. But now the human knows the data. There are cryptographic protocols that can solve this. But we can easily imagine more complicated questions that cryptography can’t solve. “Which of these two novel manuscripts has more sex scenes?” “Which of these two business plans is a riskier investment?” If Alice and Bob can agree on an AI model they both trust, they can feed the model the data, ask the question, get the answer, and then delete the model afterwards. And it’s reasonable for Alice and Bob to trust a model with questions like this. They can take the model into their own lab and test it a gazillion times until they are satisfied that it is fair, accurate, or whatever other properties they want.

The paper contains several examples where an AI TTP provides real value. This is still mostly science fiction today, but it’s a fascinating thought experiment.

Announcing the AWS CDK L2 Construct for Amazon Cognito Identity Pools

Post Syndicated from Adam Keller original https://aws.amazon.com/blogs/devops/announcing-the-aws-cdk-l2-construct-for-amazon-cognito-identity-pools/

Today we’re announcing the general availability (GA) of the new Amazon Cognito Identity Pool Level 2 (L2) construct in the AWS Cloud Development Kit (AWS CDK). This construct simplifies the creation and management of identity pools, permissions, and provider integrations by providing intent-based APIs that help users securely manage their authenticated and unauthenticated (guest) users across multiple identity providers (such as Amazon Cognito user pools, social providers like Facebook or Google, OpenID Connect, and more).

Background

The AWS CDK is an open-source software development framework that allows you to define cloud infrastructure using familiar programming languages, such as TypeScript, Python, Java, C#, and Go. The CDK provides various levels of abstraction through Constructs, which are reusable cloud components. Constructs come in three levels:

  • L1 constructs: Lowest level of constructs that are automatically generated from AWS CloudFormation resource specifications and offer no abstraction. They provide a one to one mapping to CloudFormation and can be verbose.
  • L2 constructs: Curated, high level abstractions that provide sensible defaults and reduce boilerplate code and glue logic with intuitive, intent-based APIs, making infrastructure provisioning more straightforward.
  • L3 constructs: Opinionated patterns that encapsulate multiple resources for a specific use case (for example, an entire web application stack).

Previously, developers who wanted to create Cognito Identity Pools in their CDK applications often had to work directly with L1 CloudFormation resources (for example, CfnIdentityPool and CfnIdentityPoolRoleAttachment). This led to verbose code, manual IAM role handling, and less intuitive support for multiple identity providers. The developer was responsible for all of the glue logic required when connecting Identity Pools to other AWS resources , creating IAM roles and policies and provider references on your own, which introduced more complexity.

The new AWS CDK Cognito Identity Pool L2 construct provides the following out of the box:

  • An easy way to create and manage authenticated and unauthenticated roles and permissions.
  • Built-in support for a variety of identity providers, including social providers, Amazon Cognito user pools, OpenID Connect providers, and others.
  • A high level API that reduces the amount of code and complexity required to manage the lifecycle of your identity pool.

By using this new L2 construct, you can focus on developing your application rather than the intricacies of wiring up roles, trust relationships, and provider configurations.

Using the L2

Let’s walk through an example of creating a new Cognito Identity Pool. In addition to creating the Identity Pool, we will create a Amazon DynamoDB table and then we’ll show you how to grant different levels of access for authenticated and unauthenticated users.

Create the DynamoDB Table and Cognito Identity Pool

// Create an identity pool
const identityPool = new IdentityPool(this, 'MyIdentityPool', {
    identityPoolName: 'MyIdentityPoolName',
   // Enable unauthenticated identities, disabled by default, 
   // enabling here for demonstration purposes 
   allowUnauthenticatedIdentities: true
});

// Create a new DynamoDB table
const myTable = new TableV2(this, 'MyTable', {
    partitionKey: { name: 'id', type: AttributeType.STRING },
    billing: dynamodb.Billing.onDemand()
});
// Grant read/write access on the table to authenticated users
myTable.grantReadWriteData(identityPool.authenticatedRole);

// Grant read only access to unauthenticated (guest) users
myTable.grantReadData(identityPool.unauthenticatedRole);

Let’s highlight a few key points:

  1. Single Declaration: By declaring an IdentityPool construct, you automatically get a role for authenticated users and one for unauthenticated users; however, by default, the construct disables guest access and only allows authenticated users. To enable unathenticated identities (guest access), you can set the allowUnauthenticatedIdentities parameter to true.
  2. Role and Policy Creation: You don’t have to manually define policies and roles, attach them or configure trust relationships. The L2 construct sets all of this up for you.
  3. Providers: You can specify a variety of identity providers (e.g., Google, Facebook, Amazon, Twitter, OpenID Connect, or Cognito user pools) in the authenticationProviders property.
  4. Permissions: With the roles exposed (identityPool.authenticatedRole and identityPool.unauthenticatedRole), you can easily grant or restrict fine-grained AWS resource permissions.

Multiple Authentication Providers

When using multiple providers, pass in the relevant configuration details. For example, to enable sign-in via Facebook and Google, you can provide:

const identityPool = new IdentityPool(this, 'MyIdentityPool', {
  authenticationProviders: {
    facebook: { appId: 'your-facebook-app-id' },
    google: { clientId: 'your-google-client-id' },
  },
});

The L2 takes care of generating the correct roles, trust relationships, and identity provider references behind the scenes.

Considerations for Moving to the New Construct

  1. Upgrade Path: If you currently use the L1 resources (CfnIdentityPool, CfnIdentityPoolRoleAttachment, etc.), you can migrate to the L2 construct by replacing those L1 declarations with the new IdentityPool L2. Adjust any references to custom roles or attachments to leverage the provided authenticatedRole and unauthenticatedRole properties.
  2. Compatibility: Verify the version of your AWS CDK. This L2 is available in newer CDK releases (check the changelog for specifics).
  3. Customization: If you have very specific or advanced requirements, like custom IAM conditions or policy statements, you can still refine or override the default roles or attach custom policies using the roles exposed by the L2.
  4. Alpha to GA Changes: Verify any potential feature limitations or changes in the API from the alpha to stabilized (GA) versions of the construct.

Conclusion

We’re thrilled to introduce the AWS CDK Cognito Identity Pool L2 construct, which simplifies identity pool setup and management. By leveraging a higher level API, you reduce the complexity of configuring roles and providers for your application’s user base. Whether you’re supporting social logins, guest access, or both, this new construct empowers you to build secure and scalable applications more quickly.

We invite you to get started with the Cognito Identity Pool L2 construct in your AWS CDK projects. For more information and examples, visit the AWS CDK GitHub repository and the official AWS CDK documentation. Feedback is also very important to us, so please create an issue in GitHub for any bugs or feature requests. We look forward to seeing how this new construct helps you streamline your authentication workflows and deliver exceptional user experiences.