Tag Archives: Uncategorized

Validate Your Lambda Runtime with CloudFormation Lambda Hooks

Post Syndicated from Matteo Luigi Restelli original https://aws.amazon.com/blogs/devops/validate-your-lambda-runtime-with-cloudformation-lambda-hooks/

Introduction

This post demonstrates how to leverage AWS CloudFormation Lambda Hooks to enforce compliance rules at provisioning time, enabling you to evaluate and validate Lambda function configurations against custom policies before deployment. Often these policies impact the way a software should be built, restricting language versions and runtimes. A great example is applying those policies on AWS Lambda, a serverless compute service for running code without having to provision or manage servers. While AWS Lambda already manages the deprecation of runtimes, preventing you from deploying unsupported runtimes, organizations may need to provide and enforce their specific compliance rules not directly linked to the deprecation of a specific language version.

Introducing Lambda Hooks

AWS CloudFormation Lambda Hooks are a powerful feature that allows developers to evaluate CloudFormation and AWS Cloud Control API operations against custom code implemented as Lambda functions. This capability enables proactive inspection of resource configurations before provisioning, enhancing security, compliance, and operational efficiency.

Lambda Hooks provide a mechanism to intercept and evaluate various CloudFormation operations, including resource operations, stack operations, and change set operations (they can also be used with Cloud Control API, but in this post we’re focusing on CloudFormation). By activating a Lambda Hook, CloudFormation creates an entry in your account’s registry as a private Hook, allowing you to configure it for specific AWS accounts and regions. When configuring Lambda Hooks, you can specify one or more Lambda functions to be invoked during the evaluation process. These functions can be in the same AWS account and Region as the Hook, or in another Account you own, provided proper permissions are set up. The evaluation process occurs at specific points in the CloudFormation Stack lifecycle. For instance, during stack creation, update, or deletion, the configured Lambda functions are invoked to assess the proposed changes against your defined compliance rules. Based on the evaluation results, the hook can either block the operation or issue a warning, allowing the operation to proceed.

Lambda Hooks evaluate resources before they are provisioned through CloudFormation, providing a pre-emptive layer of governance. This means that non-compliant resources are caught and prevented from being deployed, rather than requiring retroactive fixes. By leveraging Lambda Hooks, organizations can automate and standardize their compliance checks across all AWS accounts and regions. This centralized approach to policy enforcement ensures consistency and reduces the overhead of managing compliance manually.

Solution Overview

The following sections demonstrate a practical use case for AWS CloudFormation Lambda Hooks, focusing on enforcing compliance rules on AWS Lambda runtimes.

Meet AnyCompany, a forward-thinking enterprise with a robust set of compliance rules governing their software development practices. Among these rules is a strict policy on the use of specific AWS Lambda runtimes.

As they continue to embrace serverless architecture, AnyCompany faces a challenge: how to prevent the deployment of Lambda functions that use non-compliant runtimes. Given their commitment to AWS CloudFormation for deploying Lambda functions, AnyCompany is keen to leverage the power of AWS CloudFormation Lambda Hooks.

We’ll explore the setup process, demonstrate the hook in action, and discuss the broader implications for maintaining compliance in a dynamic cloud environment.

Architecture

The following architecture highlights the implementation of the Lambda Hook. In this implementation, we are using AWS CloudFormation Lambda Hooks to intercept the deployment of Lambda Functions and perform the compliance checks on these resources. The Lambda Hook will interact with an AWS Lambda Function, which will perform the compliance checks. Finally, we’re using AWS Systems Manager Parameter Store to store the Configuration Parameter which contains the list of permitted Lambda Runtimes.
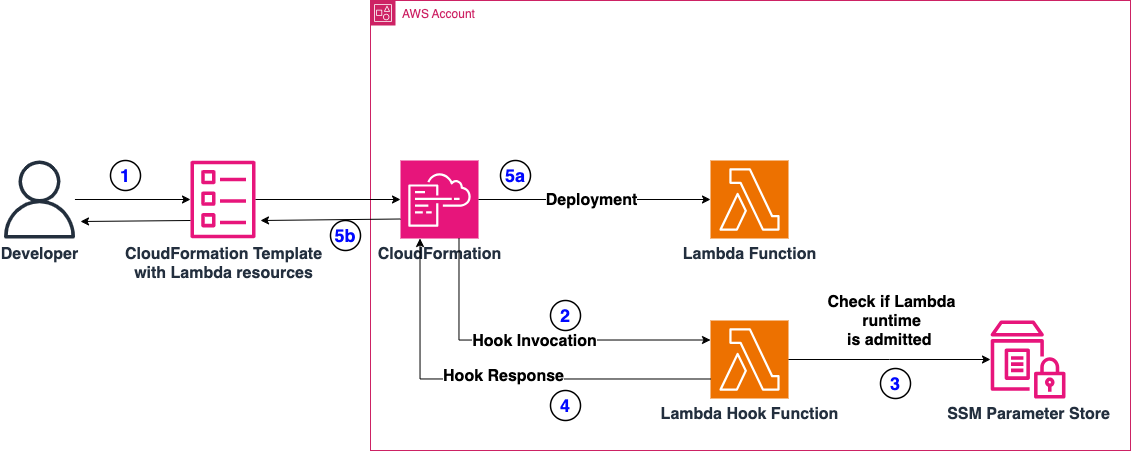
Figure 1: Architecture of the Solution

Figure 1: Architecture of the Solution

  1. A Developer (or a CI/CD pipeline) deploys a CloudFormation stack containing Lambda functions.
  2. CloudFormation invokes the respective Lambda Hook, which is configured to intercept operations on AWS Lambda Resources. We are setting this hook to “FAIL” deployment in case checks are not successful.
  3. The Lambda Hook checks if the runtime of the Lambda is admitted or violates Company’s compliance. To do this, it checks if the runtime is present on a pre-configured list of admitted runtimes saved as Parameter in AWS Systems Manager Parameter Store. Keep in mind that we’re using SSM Parameter Store to store the configuration for this specific example, but other alternatives may be viable as well (Amazon DynamoDB, AWS Secrets Manager, or AppConfig lambda-function-settings-check Preventive Rule)
  4. The Lambda Hook, after checking runtime compliance, replies:
    • With a failure, if the Lambda runtime is not compliant
    • With a success, if the Lambda runtime is compliant
  5. Depending on the response of the Lambda Hook, the deployment may or not take place.

Repository Structure

You can find all the code for this solution at this link. Here’s the repository structure:

.
├── README.md
├── deploy.sh
├── cleanup.sh
├── hook-lambda
│ ├── index.ts
│ ├── package.json
│ ├── services
│ │ └── parameter-store.ts
│ └── tsconfig.json
├── sample
│ ├── deploy_sample.sh
│ ├── cleanup_sample.sh
│ └── lambda_template.yml
└── template.yml
  • hook-lambda: directory containing all the code related to the CloudFormation Lambda Hook (Validation Lambda Function, and the CloudFormation template for the Solution)
  • sample: directory containing the code of the sample used to test the CloudFormation Lambda Hook
  • deploy.sh: utility script to deploy the Solution via AWS CLI
  • cleanup.sh: utility script to clean up the AWS CloudFormation Hook infrastructure via the AWS CLI
  • template.yml: AWS CloudFormation Template containing all the AWS Resources involved in the Solution

Prerequisites

You must have the following prerequisites for this solution:

  • An AWS account or sign up to create and activate one.
  • The following software installed on your development machine:
  • Install the AWS Command Line Interface (AWS CLI) and configure it to point to your AWS account.
  • Install Node.js and use a package manager such as npm.
  • Appropriate AWS credentials for interacting with resources in your AWS account.

Walkthrough

Creating the AWS Lambda Validation Function – Lambda Code

The CloudFormation Lambda Hook interacts with a specific Lambda (referred to as Validation Lambda throughout the rest of this post), which gets invoked during CloudFormation CREATE and UPDATE STACK operations involving Lambda Functions. The goal is to check if these Lambda functions have runtimes that comply with AnyCompany’s rules.

Below is the detailed description of the steps that the Validation Lambda function handler follows (the code is written in Typescript).

First, the Validation Lambda retrieves an environment variable containing the SSM Parameter Store parameter name which contains the compliant runtimes list. Additionally, safety checks ensure that only Lambda Resources are considered and that their Runtime property is defined.

Note that both safety checks could be skipped, since the Hook should already be configured to interact only with Lambda Resources and the Lambda’s Runtime property is always required. However, they remain in place to demonstrate how to retrieve this information from the Lambda Hook event in your handler.

const parameterName = process.env.PERMITTED_RUNTIMES_PARAM;
if (!parameterName) {
	throw new Error('Permitted Runtimes Parameter is not set');
}

const resourceProperties = event.requestData.targetModel.resourceProperties;
// Check if this is a Lambda function resource
if (event.requestData.targetType !== 'AWS::Lambda::Function') {
console.log("Resource is not a Lambda function, skipping");
	return {
		hookStatus: 'SUCCESS',
		message: 'Not a Lambda function resource, skipping validation',
		clientRequestToken: event.clientRequestToken
	}
}

// Check runtime version compliance
const runtime = resourceProperties.Runtime;
if (!runtime) {
	console.log("Runtime not defined, failing");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: 'Runtime is required for Lambda functions',
		clientRequestToken: event.clientRequestToken
	}
}

Then the Validation Lambda retrieves the value of the Configuration Parameter from SSM Parameter Store through a utility class called ParameterStoreService. For this post, consider that the value inside that Configuration Parameter is a list of strings, where each string contains one of the possible Lambda runtime values that you can find here (e.g. nodejs22.x,nodejs20.x,python3.11,python3.10,java17,java11,dotnet6). After retrieving the value, the Validation Lambda checks if the runtime of the Lambda Resource complies with the configured admitted runtimes. If the runtime is not compliant, you’ll receive a properly formatted response with FAILURE as hookStatus, otherwise the response will contain a SUCCESS hookStatus.

// Retrieve configuration from Parameter Store
const compliantRuntimes = await parameterStoreService.getParameterFromStore(parameterName);

// Check if Lambda runtime is permitted or not
if (!compliantRuntimes.includes(runtime)) {
console.log("Runtime " + runtime + " not compliant ");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: `Runtime ${runtime} is not compliant. Please use one of: ${compliantRuntimes.join(', ')}`,
		clientRequestToken: event.clientRequestToken
	}
}

return {
	hookStatus: 'SUCCESS',
	message: 'Runtime version compliance check passed',
	clientRequestToken: event.clientRequestToken
}

For more information about the possible response values of CloudFormation Lambda Hooks Lambda, have a look at this link.

Creating the validation Lambda – Lambda CloudFormation definition

The Validation Lambda function will be deployed via CloudFormation, in the same Stack with the CloudFormation Lambda Hook definition and the AWS Systems Manager Parameter Store Parameter. Here’s the fragment of the CloudFormation Template containing its definition:

# Lambda Function
ValidationFunction:
	Type: AWS::Lambda::Function
	Properties:
		Handler: index.handler
		Role: !GetAtt LambdaExecutionRole.Arn
		Code:
			S3Bucket: !Ref DeploymentBucket
			S3Key: hook-lambda.zip
		Runtime: nodejs22.x
		Timeout: 60
		MemorySize: 128
		Environment:
			Variables:
				PERMITTED_RUNTIMES_PARAM: !Ref ParameterStoreParamName

You’ll need to associate an IAM Role with proper permissions to access the AWS Systems Manager Parameter Store Parameter:

# Lambda Function Role
LambdaExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: lambda.amazonaws.com
            Action: sts:AssumeRole
      ManagedPolicyArns:
        - arn:aws:iam::aws:policy/service-role/AWSLambdaBasicExecutionRole
		
# IAM Policy to access Parameter Store
ParameterStoreAccessPolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref LambdaExecutionRole
      PolicyName: ParameterStoreAccess
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - ssm:GetParameter
            Resource: !Sub arn:aws:ssm:${AWS::Region}:${AWS::AccountId}:parameter${ParameterStoreParamName}

Creating the CloudFormation Lambda Hook

At this point, you only need to author a proper CloudFormation Lambda Hook. The Hook requires:

  • To be activated during the CREATE and UPDATE CloudFormation operations,
  • To consider only AWS::Lambda::Function CloudFormation resources
  • To act during Pre Provisioning of CloudFormation templates
  • To target Stack and Resource Operations
  • Target the already defined Lambda Validation function

Here’s the definition in the CloudFormation template:

# Lambda Hook
ValidationHook:
    Type: AWS::CloudFormation::LambdaHook
    Properties:
      Alias: Private::Lambda::LambdaResourcesComplianceValidationHook
      LambdaFunction: !GetAtt ValidationFunction.Arn
      ExecutionRole: !GetAtt HookExecutionRole.Arn
      FailureMode: FAIL
      HookStatus: ENABLED
      TargetFilters:
        Actions:
          - CREATE
          - UPDATE
        InvocationPoints:
          - PRE_PROVISION
        TargetNames:
          - AWS::Lambda::Function
      TargetOperations:
        - RESOURCE
        - STACK

Please note that the above template contains a reference to an IAM Role because the Hook requires proper permissions to call the target (Lambda Function). Here’s the IAM Role definition:

# Hook Execution Role
HookExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: hooks.cloudformation.amazonaws.com
            Action: sts:AssumeRole

# IAM Policy for Lambda Invocation
LambdaInvokePolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref HookExecutionRole
      PolicyName: LambdaInvokePolicy
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - lambda:InvokeFunction
            Resource: !GetAtt ValidationFunction.Arn

Configuring the compliant runtimes – Using Systems Manager Parameter Store

AWS Systems Manager Parameter Store is a secure, hierarchical storage service for configuration data management and secrets management, allowing users to store and retrieve data such as configurations, database strings etc. as parameter values.

In this specific example, we’ll leverage Parameter Store to store our permitted Lambda runtimes configuration. This configuration value is a StringList parameter, containing a comma-separated list of permitted runtimes. Here’s the fragment of the CloudFormation template that defines the Parameter:

# Parameter Store Parameter
ConfigParameter:
    Type: AWS::SSM::Parameter
    Properties:
      Name: !Ref ParameterStoreParamName
      Type: StringList
      Value: !Ref ParameterStoreDefaultValue
      Description: "Configuration for Lambda Hook"

Please note the usage of CloudFormation parameters for the ‘Name’ and ‘Value’ properties, allowing for dynamic input when deploying the CloudFormation template.

Deploying the Solution

To deploy the solution you can leverage the script deploy.sh in the root folder of the repository. This script will perform the following actions:

  • Compile and build the Validation Lambda Function
  • Create an Amazon S3 Bucket to store the CloudFormation Template
  • Upload the CloudFormation template and Lambda code to the S3 Bucket
  • Deploy the CloudFormation template

Testing the Lambda Hook

To test the CloudFormation Lambda Hook, deploy a simple testing CloudFormation template containing a Hello World Lambda function. First, test the Lambda configured with a permitted Lambda runtime, then modify the template to configure the Lambda with a non-compliant runtime.

Here’s the initial definition of the testing CloudFormation Template:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs22.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

Please note that the Runtime value is nodejs22.x, which is currently in the list of permitted runtimes. The expectation is that the deployment of this function will succeed.

Deploy this template via the AWS CLI:

aws cloudformation deploy \
--template-file ./lambda_template.yml \
--capabilities CAPABILITY_IAM \
--stack-name lambda-sample

Check the CloudFormation Console:
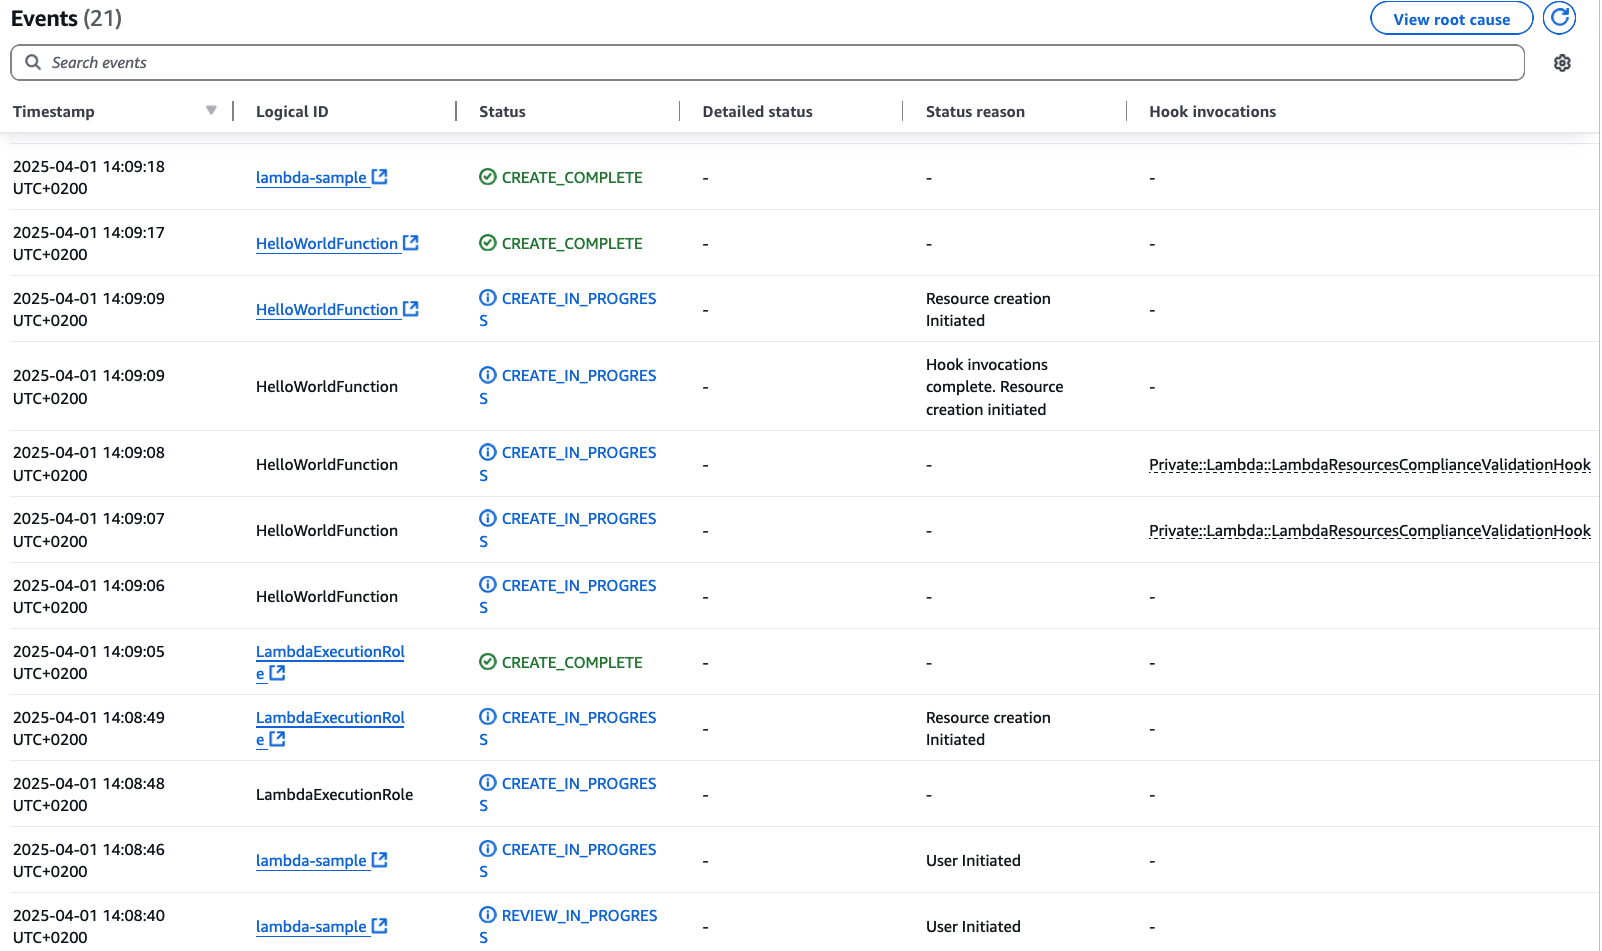
CloudFormation Console showing successful Stack deployment

Figure 2: CloudFormation Console showing successful Stack deployment

As expected, the deployment was successful. You can also see that the CloudFormation Lambda Hook has been invoked by taking a look at the CloudWatch Logs:
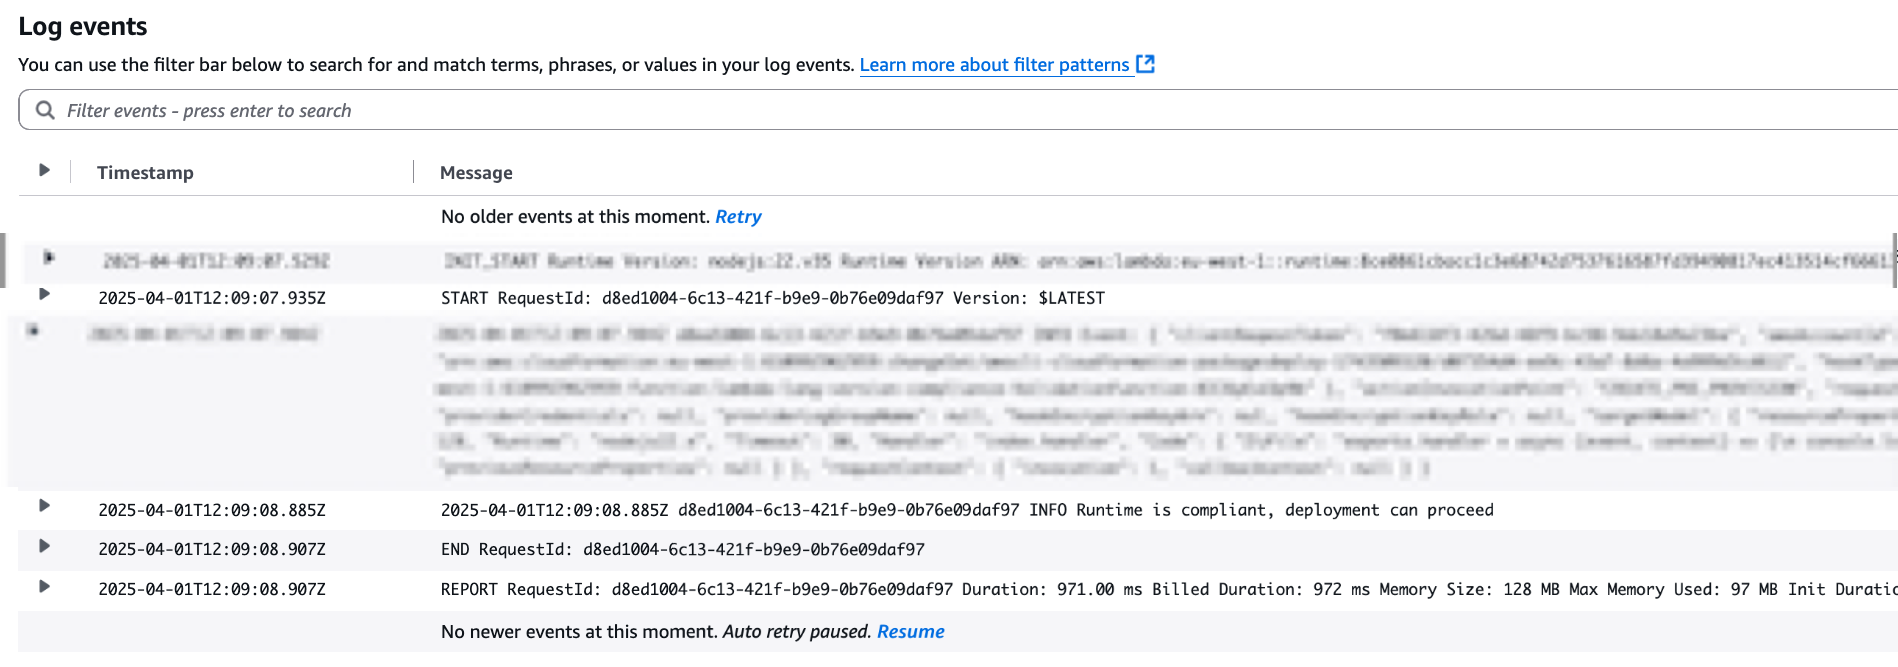
Validation Lambda Function Logs with successful validation

Figure 3: Validation Lambda Function Logs with successful validation

Now modify the original sample Template in order to set a Lambda Runtime which is not inside the list of permitted runtimes:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs18.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

Deploy this template via AWS CLI with the same command used before and check the CloudFormation Console:
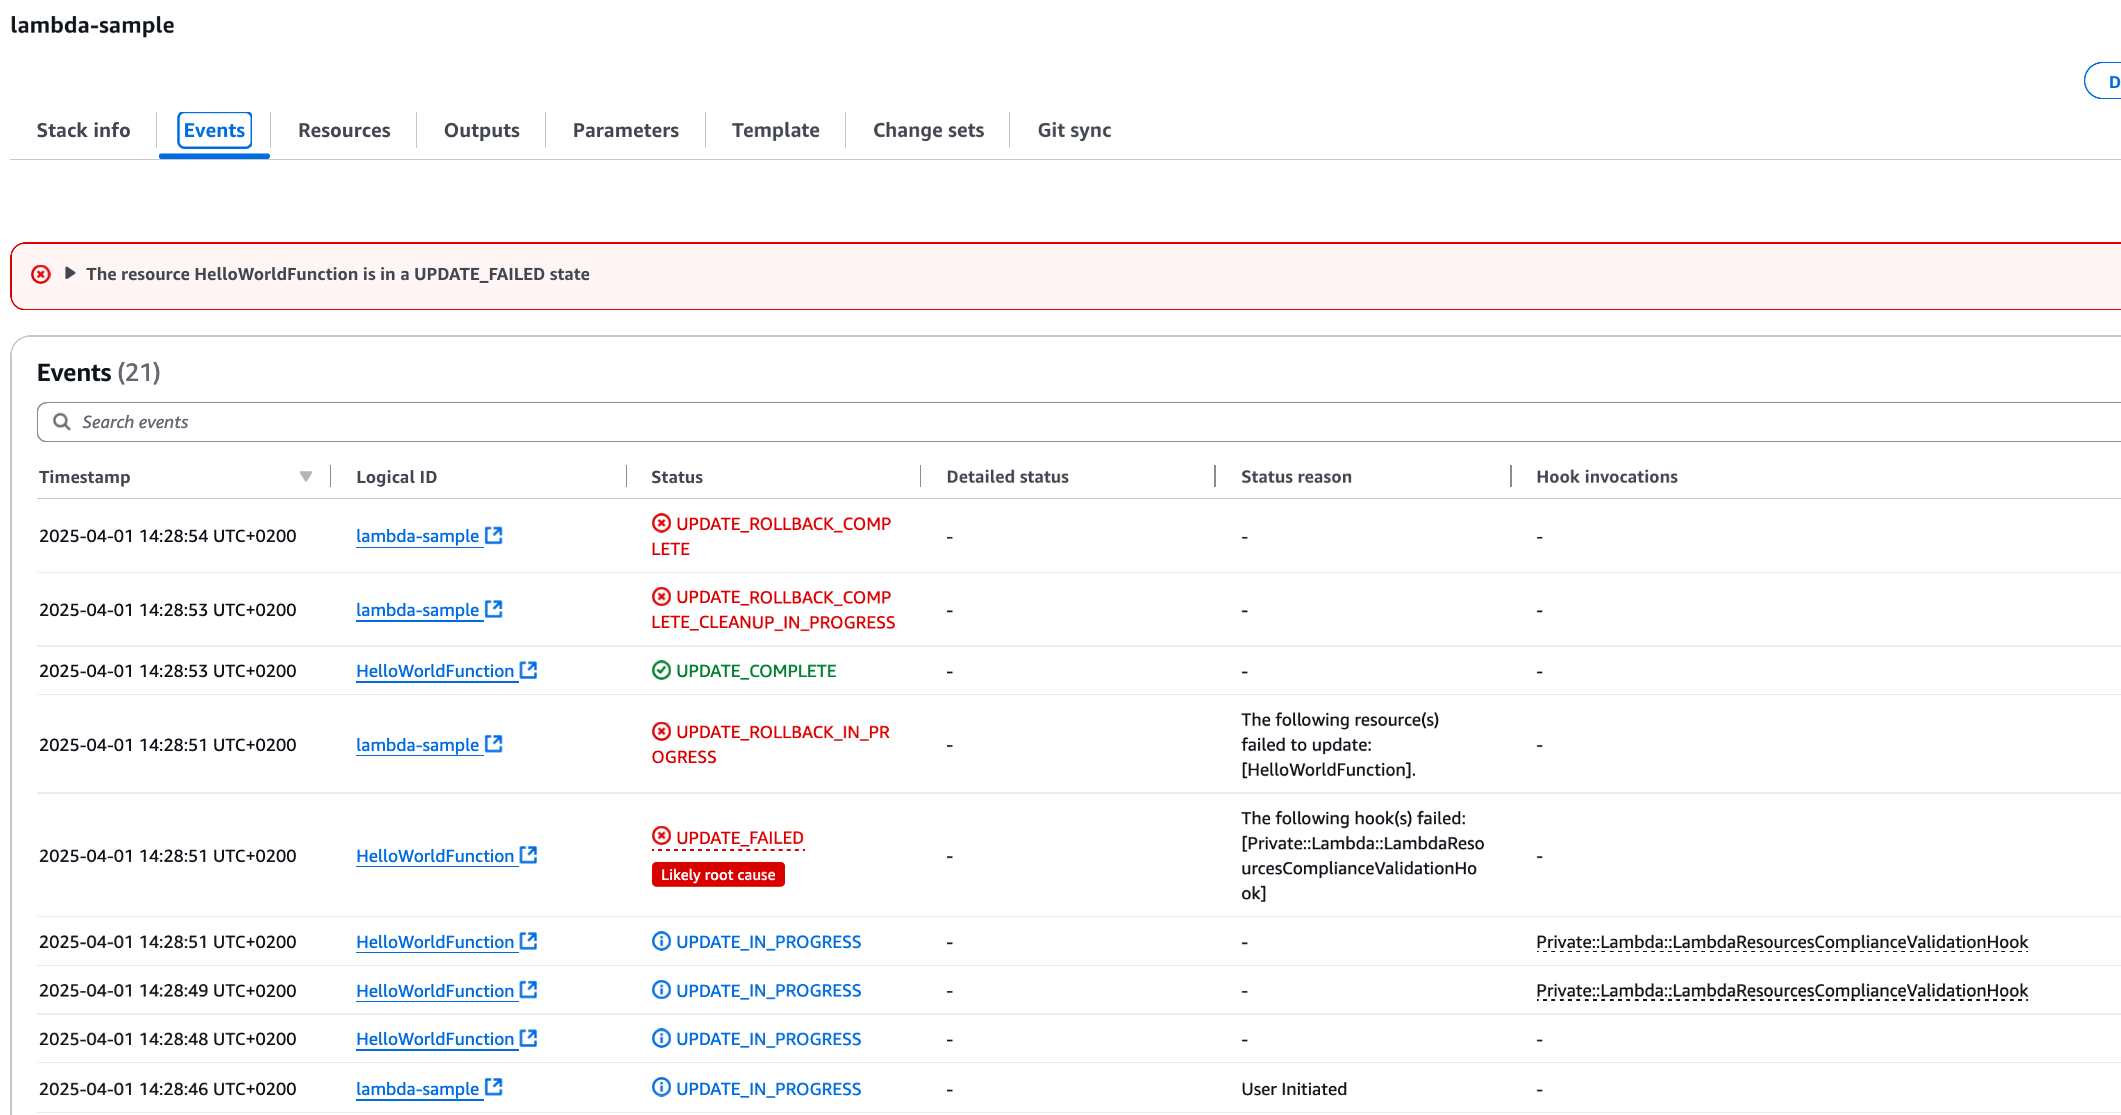
CloudFormation Console showing failed Stack deployment due to Hook intervention

Figure 4: CloudFormation Console showing failed Stack deployment due to Hook intervention

As expected, the deployment was not successful. The CloudFormation Lambda Hook has been invoked, and since the Lambda Runtime was not present in the permitted runtimes list, the deployment failed.

You can also see that the hook failed In the CloudWatch Logs:
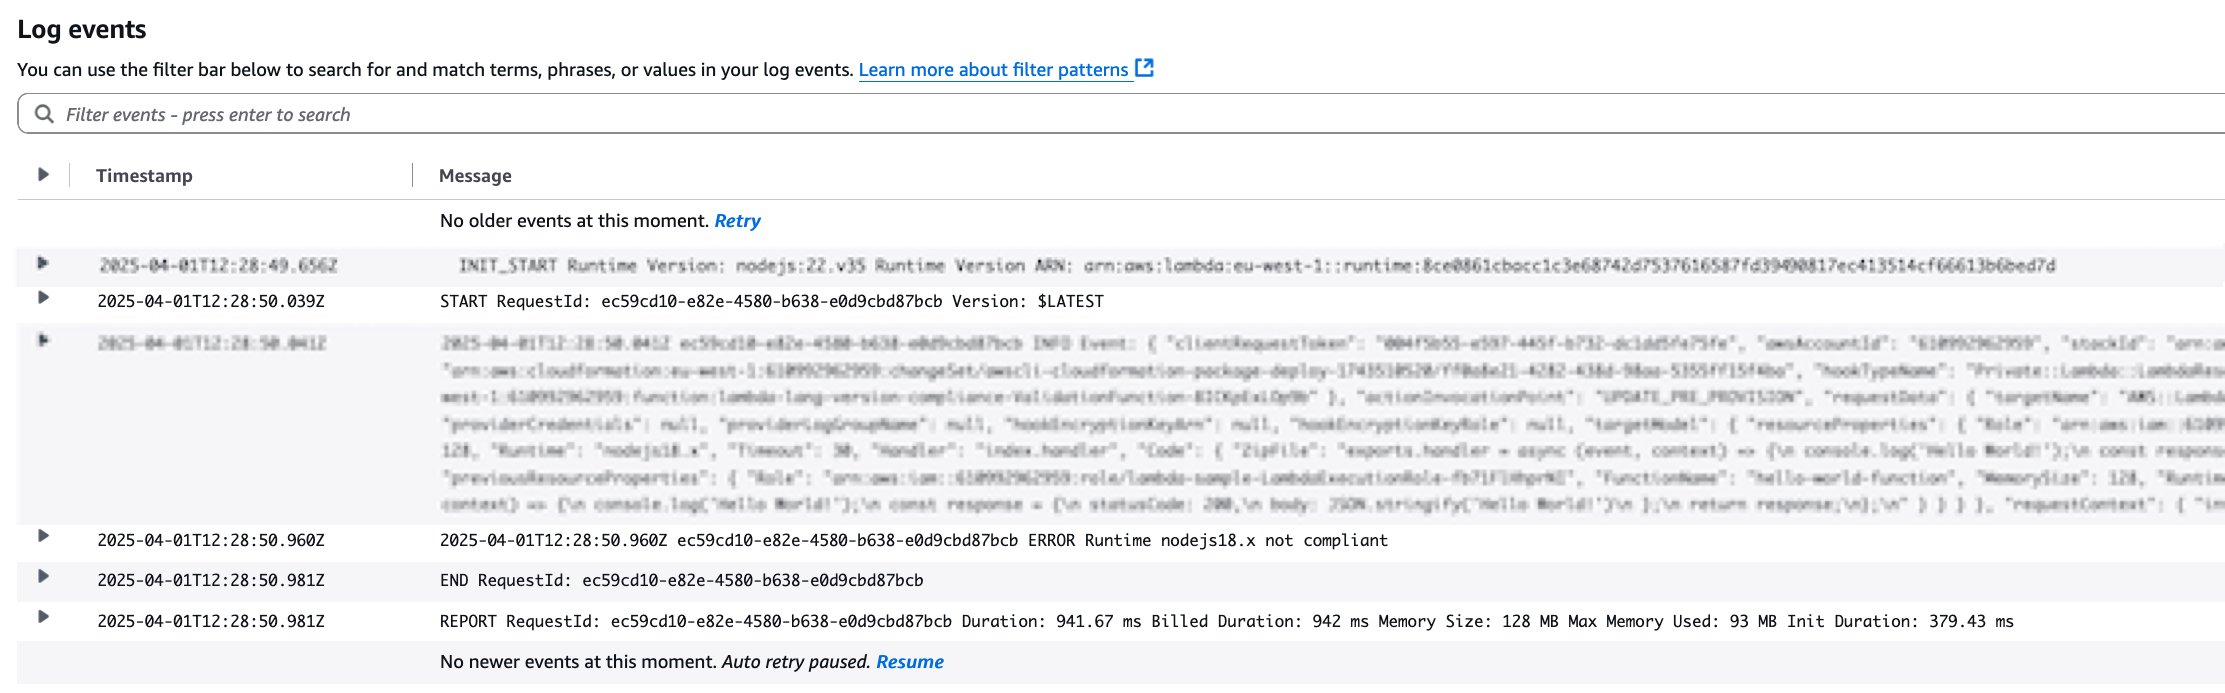
Validation Lambda Function Logs with validation error

Figure 5: Validation Lambda Function Logs with validation error

Cleaning up

To clean up the resources related to the sample, you can run the script cleanup_sample.sh inside the sample folder. This script will delete the sample’s CloudFormation Template through the AWS CLI.

To cleanup the resources related to the solution described above and based on AWS CloudFormation Lambda Hook, you can leverage the script cleanup.sh in the root folder of the repository. This script will perform the following actions:

  • Delete the CloudFormation Stack
  • Empty the S3 Bucket used for the deployment of the Stack
  • Delete the S3 Bucket

Conclusion

In this post, you explored the implementation of CloudFormation Hooks to enforce runtime compliance in Lambda functions across your AWS infrastructure. By leveraging the Lambda hook’s capabilities, you learned how to create a preventative control that validates Lambda runtime configurations before deployment.

By activating the Lambda hook and implementing a custom Lambda function validator, you established an automated mechanism to ensure that only compliant runtimes are used within your organization’s Lambda functions during CloudFormation stack creation and updates. The solution’s integration with common development tools like AWS CLI, AWS SAM, CI/CD pipelines, and AWS CDK makes it straightforward to implement these controls within existing workflows, eliminating the need for manual runtime checks or post-deployment remediation.

The validation approach demonstrated in this post extends beyond Lambda runtimes and can be adapted to different AWS Resources supported by CloudFormation, allowing you to enforce policies on different infrastructure components offered by AWS.

About the author

Matteo Luigi Restelli

Matteo Luigi Restelli is an AWS Sr. Partner Solutions Architect. He mainly focuses on Italian Consulting AWS Partners and is also specialized in Infrastructure as Code, Cloud Native App Development and DevOps. Outside of work, he enjoys swimming, rock & roll music and learning something new everyday especially in Computer Science space.

Stella Hie

Stella Hie is a Sr. Product Manager Technical for AWS Infrastructure as Code. She focuses on proactive control and governance space, working on delivering the best experience for customers to use AWS solutions safely. Outside of work, she enjoys hiking, playing piano, and watching live shows.

Rational Astrologies and Security

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/rational-astrologies-and-security.html

John Kelsey and I wrote a short paper for the Rossfest Festschrift: “Rational Astrologies and Security“:

There is another non-security way that designers can spend their security budget: on making their own lives easier. Many of these fall into the category of what has been called rational astrology. First identified by Randy Steve Waldman [Wal12], the term refers to something people treat as though it works, generally for social or institutional reasons, even when there’s little evidence that it works—­and sometimes despite substantial evidence that it does not.

[…]

Both security theater and rational astrologies may seem irrational, but they are rational from the perspective of the people making the decisions about security. Security theater is often driven by information asymmetry: people who don’t understand security can be reassured with cosmetic or psychological measures, and sometimes that reassurance is important. It can be better understood by considering the many non-security purposes of a security system. A monitoring bracelet system that pairs new mothers and their babies may be security theater, considering the incredibly rare instances of baby snatching from hospitals. But it makes sense as a security system designed to alleviate fears of new mothers [Sch07].

Rational astrologies in security result from two considerations. The first is the principal­-agent problem: The incentives of the individual or organization making the security decision are not always aligned with the incentives of the users of that system. The user’s well-being may not weigh as heavily on the developer’s mind as the difficulty of convincing his boss to take a chance by ignoring an outdated security rule or trying some new technology.

The second consideration that can lead to a rational astrology is where there is a social or institutional need for a solution to a problem for which there is actually not a particularly good solution. The organization needs to reassure regulators, customers, or perhaps even a judge and jury that “they did all that could be done” to avoid some problem—even if “all that could be done” wasn’t very much.

Cell Phone OPSEC for Border Crossings

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/cell-phone-opsec-for-border-crossings.html

I have heard stories of more aggressive interrogation of electronic devices at US border crossings. I know a lot about securing computers, but very little about securing phones.

Are there easy ways to delete data—files, photos, etc.—on phones so it can’t be recovered? Does resetting a phone to factory defaults erase data, or is it still recoverable? That is, does the reset erase the old encryption key, or just sever the password that access that key? When the phone is rebooted, are deleted files still available?

We need answers for both iPhones and Android phones. And it’s not just the US; the world is going to become a more dangerous place to oppose state power.

Adopting Amazon Q Developer in Enterprise Environments

Post Syndicated from Rene-Martin Tudyka original https://aws.amazon.com/blogs/devops/adopting-amazon-q-developer-in-enterprise-environments/

Increasing developer productivity has been a persistent challenge for senior leaders over the past decades. With the rise of generative artificial intelligence (AI), a new wave of innovation is transforming how software teams work. Generative AI tools like Amazon Q Developer are emerging as game-changers, supporting developers across the entire software development lifecycle. But how are large-scale organizations successfully adopting this AI-assisted approach? This document shares good practices I have discovered through working with enterprise customers navigating this technological transformation.

A common misperception still is that a developer is more productive when they write code faster. But a median developer spends less than one hour per day writing code, as a study conducted by software.com in 2022 shows. This makes clear that there are other aspects to consider when it comes to building an application and running it in production. Generative AI tools for developers, such as Amazon Q Developer, started as coding companions that provided inline completions. As the technology evolved, Amazon Q Developer is now able to support developers across the entire software development life cycle.

The Change Challenge

Generative AI offers new and interesting ways for developers to solve challenges and to support them in their daily work. But taking advantage of those opportunities takes some time. It introduces a noticeable change to their familiar ways of working and therefore it is much about forming a new habit. This, according to science, usually takes a minimum of two months. Teams need the space and permission to play with this new approach and to find out what works best for them. Expecting them to adopt a new way of working while expecting the same (or higher) level of output at the same time will only lead to teams falling back to what they know works. For customers that successfully have adopted Amazon Q Developer I have seen them reducing the delivery expectations to give space to learn, and having required teams to share learnings in return.

Additionally, as in any other large change project there is a significant cultural aspect to consider. If people feel intrinsically convinced by the value and benefits of an AI-supported approach to software engineering they will use it. “Simply ordering from above” will not help making an adoption successful. But building community, experimenting, learning, and sharing successes will. “Culture eats strategy for breakfast”, as the management visionary Peter Drucker said.

Keeping that in mind it is clear that there is no one-size-fits-all prescriptive way of successfully introducing generative AI tools for developers in your organization. It very much depends on your individual culture, goals, challenges, people, skills, and technology stack for example. However, there are a number of principles and good practices that work well with several of our large-scale customers who have successfully adopted Amazon Q Developer.

Best Practices for Successful Adoption

The following illustration describes the change management cycle and recommended activities for adopting AI-assisted software development.

The change management cycle – align, plan, roll out, reflect and repeat

Figure 1. The change management cycle

1. Secure Top-Down Commitment

Secure executive buy-in for adopting AI-assisted software development because this is a powerful sign for the organization. It helps to remove roadblocks and to promote successes across the organization. An executive sponsor links the adoption of AI-assisted software development to the strategic goals of the organization, will help resolving prioritization and capacity conflicts. Invite the sponsor to a kick-off meeting. Include them for the discussion of goals and success criteria, and keep them updated on progress, success stories, and challenges.

2. Become Clear on Goals and Success Criteria

Simply rolling out Generative AI tools to a large developer base won’t be enough. You need to be clear what you expect from such an adoption for your organization, for your developers, and for your business. It is important for you to understand your organization’s pain points from a developer experience perspective and how they affect your development productivity. These likely differ between different personas, like Software Developers and DevOps Engineers. For example, are your applications lacking test coverage or is your code lacking documentation, which creates a maintenance burden, and makes it difficult to onboard new developers? Is handling legacy code risky and time-consuming so that you avoid necessary upgrades because of the complexity and effort? Is troubleshooting applications locally or in production eating up your developers’ time? Or are you facing challenges caused by hard-to-find security issues in the code? What is it that you want to achieve by introducing an AI-assisted development approach, and why?

3. Establish Ownership

Adopting a new approach like the use of generative AI in software development at scale leads to many change management and coordination tasks. Those are related to getting access to the tool, enablement for new users, budget planning, measuring success and creating transparency on problems, creating momentum and making sure the adoption sustains, amongst others. Therefore, introducing a Customer Champion as a leader who coordinates the business and technology related aspects of the adoption is a common approach. They will connect the strategic goals of the organization with the tactical activities necessary for the implementation. If your adoption is spanning multiple different business units with larger developer bases consider establishing this role for each of them, forming a team that collaborates across your whole organization. Key responsibilities of the Customer Champion are to bring the right people together to successfully work on the adoption, to create transparency on status, and to address impediments early on.

4. Introduce Metrics

Once you have gained clarity on the specific pain points and goals for your organization, the next step is to determine the appropriate metrics to measure the success of your efforts. For example, you can measure the impact of using Amazon Q Developer on onboarding new developers by tracking the time to first commit against a previously established baseline average. Comparing the time it takes to complete certain tasks – like writing and integrating code, fixing bugs, setting up or upgrading environments, the time it takes to build a new feature, or by comparing sprint velocity before and after the introduction of Amazon Q Developer will give you further indications. But keep in mind that there is ambiguity in these metrics because they are impacted by different factors.

Focusing on developer experience and productivity, monitor the development of your established measurement framework, like DORA, SPACE, or GSM. SPACE in particular, with its “Satisfaction & Well-Being” dimension, pays close attention to how software developers perceive their work and how satisfied they are with their own productivity. Tools like Amazon Q Developer have shown a positive effect here, as for example a McKinsey study shows. They help to free developers from tasks that are perceived as toil, like repetitive and boring grunt work that doesn’t necessarily bring business value. To measure this impact on perceived productivity, customers sometimes design simple surveys, asking developers questions like “in percentage, how would you estimate the impact of using Amazon Q Developer on your productivity” or “on a scale from 1-5, how is Amazon Q Developer impacting the satisfaction with your day-to-day work?”

As a last dimension, understanding the general usage of Amazon Q Developer across your organization is important. Monitor the number active subscriptions, accepted code recommendations, or the number of executed security scans from the Amazon Q Developer dashboard. That way you will get an understanding for the acceptance of the tool in your developer base. Correlate this information with the success metrics you defined.

5. Start Small

When “rolling out” an AI-assisted software development approach, keep the technology adoption lifecycle and Everett Roger’s bell curve in mind. It describes that adoption of a new technology usually starts with a few “innovators”, followed by a small fraction of “early adopters”. Only if those early groups demonstrate convincing success, the majority of users will follow the adoption. To settle on this model will help you making the adoption of AI-assisted development successful in your organization.

Start small. Identify your tech innovators, or champions, who are enthusiastic to support the introduction of Amazon Q Developer and to advocate the approach in your organization. With them, build a team or a Center of Excellence (COE) that will help with identifying early adopters across your development teams, building technical and enablement foundations for onboarding users, creating roll-out plans, and evangelizing and sustaining the adoption. The champions will act as a bridge between your adoption program team and your users. They can provide insights and feedback on the adoption and come up with recommendations.

6. Create Momentum

Now that you have your foundations in place it is time to create momentum and onboard your early adopters to Amazon Q Developer. Start with a communication plan to raise awareness, to share updates and success stories, and to collect feedback from the users. You will need to create training material covering organization-specific resources (how to get access, for example, or which communication channels and contact points exist), user guides, tutorials, and pointers to relevant documentation and online resources. Consider creating your own prompt library, documenting prompts for Amazon Q Developer that your users find particularly helpful. There are community projects like promptz.dev that can deliver inspiration. Especially for new users this will have a lot of value for getting up to speed.

Consider how to integrate learning pathways with your organization’s learning platform moving forward. These should include the company-specific experience and knowledge you collect. In addition, it might be helpful to integrate external offers, like classroom trainings or workshop formats offered by AWS.

Hands-on technical enablement workshops will help your early adopters jumpstarting their experience. AWS offers multiple formats that can be tailored to your individual context. These include service deep-dives with Amazon Q Developer specialists, Immersion Days and hackathon support for teams to hands-on experience the tool in a guided, interactive format, or joined proof-of-value engagements. Your AWS account team will provide you more information.

7. Sustain and Scale Adoption

At that point you will have established Amazon Q Developer among an initial segment of your developer base. However, keeping Roger’s adoption curve in mind the largest part of the adoption still lies ahead of you. To facilitate the it across your whole organization, focus on delivering enablement workshops for the teams to be onboarded. These will be led by your champions and incorporate your organization-specific practices and knowledge.

To sustain the adoption, make sure the existing user base stays active. Continue offering exchange and support, collecting feedback, updating your enablement material, sharing updates on the latest developments for Amazon Q Developer, and reviewing your metrics. Create visibility across your organization for the accomplishments and positive experiences. Let user talk about the impact Amazon Q Developer has on their work. This will help building momentum. Nurture community building around your users of AI-assisted development.

Establish regular office hours with your champions for providing support and enablement to your users of Amazon Q Developer. This will facilitate the continuous gathering of feedback to improve documentation and enablement materials, collect and promote success stories, and validate the adoption approach. Additionally, establish a consistent communications and reporting cadence to keep all relevant stakeholders informed of key metrics, updates, feedback, and success stories. This ensures the alignment of the adoption of AI-assisted development with your strategic goals and expectations.

8. Inspect and Adapt

In addition, keep reflecting on the goals and metrics you came up with from a strategic perspective. Are they developing in the right direction? Are your pain points still the same? Should you move your focus to different aspects of the software development life cycle? And how might new capabilities of Amazon Q Developer support your goals?

Conclusion

By following the outlined approach, large organizations can successfully navigate the challenges of adopting Amazon Q Developer. The approach addresses technical, cultural, and organizational aspects of the adoption, increasing the likelihood of realizing the full potential of AI-assisted development across the enterprise.

If you are looking for advice or support during your adoption journey, your AWS Account Team will connect you with experts on Amazon Q Developer, provide you information on training and enablement, and support you with setting up a successful rollout program for your organization. To learn more about how Amazon Q Developer’s capabilities support the whole software development lifecycle, visit the product page or have a look at the documentation.

About the Author

Rene-Martin Tudyka is a Senior Customer Solutions Manager at AWS and provides guidance and support for enterprise customers on their cloud maturity journey. He has a long background in developing highly performant IT organizations and in successful large-scale cloud adoption.

The Signal Chat Leak and the NSA

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/the-signal-chat-leak-and-the-nsa.html

US National Security Advisor Mike Waltz, who started the now-infamous group chat coordinating a US attack against the Yemen-based Houthis on March 15, is seemingly now suggesting that the secure messaging service Signal has security vulnerabilities.

"I didn’t see this loser in the group," Waltz told Fox News about Atlantic editor in chief Jeffrey Goldberg, whom Waltz invited to the chat. "Whether he did it deliberately or it happened in some other technical mean, is something we’re trying to figure out."

Waltz’s implication that Goldberg may have hacked his way in was followed by a report from CBS News that the US National Security Agency (NSA) had sent out a bulletin to its employees last month warning them about a security "vulnerability" identified in Signal.

The truth, however, is much more interesting. If Signal has vulnerabilities, then China, Russia, and other US adversaries suddenly have a new incentive to discover them. At the same time, the NSA urgently needs to find and fix any vulnerabilities quickly as it can—and similarly, ensure that commercial smartphones are free of backdoors—access points that allow people other than a smartphone’s user to bypass the usual security authentication methods to access the device’s contents.

That is essential for anyone who wants to keep their communications private, which should be all of us.

It’s common knowledge that the NSA’s mission is breaking into and eavesdropping on other countries’ networks. (During President George W. Bush’s administration, the NSA conducted warrantless taps into domestic communications as well—surveillance that several district courts ruled to be illegal before those decisions were later overturned by appeals courts. To this day, many legal experts maintain that the program violated federal privacy protections.) But the organization has a secondary, complementary responsibility: to protect US communications from others who want to spy on them. That is to say: While one part of the NSA is listening into foreign communications, another part is stopping foreigners from doing the same to Americans.

Those missions never contradicted during the Cold War, when allied and enemy communications were wholly separate. Today, though, everyone uses the same computers, the same software, and the same networks. That creates a tension.

When the NSA discovers a technological vulnerability in a service such as Signal (or buys one on the thriving clandestine vulnerability market), does it exploit it in secret, or reveal it so that it can be fixed? Since at least 2014, a US government interagency "equities" process has been used to decide whether it is in the national interest to take advantage of a particular security flaw, or to fix it. The trade-offs are often complicated and hard.

Waltz—along with Vice President J.D. Vance, Defense Secretary Pete Hegseth, and the other officials in the Signal group—have just made the trade-offs much tougher to resolve. Signal is both widely available and widely used. Smaller governments that can’t afford their own military-grade encryption use it. Journalists, human rights workers, persecuted minorities, dissidents, corporate executives, and criminals around the world use it. Many of these populations are of great interest to the NSA.

At the same time, as we have now discovered, the app is being used for operational US military traffic. So, what does the NSA do if it finds a security flaw in Signal?

Previously, it might have preferred to keep the flaw quiet and use it to listen to adversaries. Now, if the agency does that, it risks someone else finding the same vulnerability and using it against the US government. And if it was later disclosed that the NSA could have fixed the problem and didn’t, then the results might be catastrophic for the agency.

Smartphones present a similar trade-off. The biggest risk of eavesdropping on a Signal conversation comes from the individual phones that the app is running on. While it’s largely unclear whether the US officials involved had downloaded the app onto personal or government-issued phones—although Witkoff suggested on X that the program was on his "personal devices"—smartphones are consumer devices, not at all suitable for classified US government conversations. An entire industry of spyware companies sells capabilities to remotely hack smartphones for any country willing to pay. More capable countries have more sophisticated operations. Just last year, attacks that were later attributed to China attempted to access both President Donald Trump and Vance’s smartphones. Previously, the FBI—as well as law enforcement agencies in other countries—have pressured both Apple and Google to add "backdoors" in their phones to more easily facilitate court-authorized eavesdropping.

These backdoors would create, of course, another vulnerability to be exploited. A separate attack from China last year accessed a similar capability built into US telecommunications networks.

The vulnerabilities equities have swung against weakened smartphone security and toward protecting the devices that senior government officials now use to discuss military secrets. That also means that they have swung against the US government hoarding Signal vulnerabilities—and toward full disclosure.

This is plausibly good news for Americans who want to talk among themselves without having anyone, government or otherwise, listen in. We don’t know what pressure the Trump administration is using to make intelligence services fall into line, but it isn’t crazy to worry that the NSA might again start monitoring domestic communications.

Because of the Signal chat leak, it’s less likely that they’ll use vulnerabilities in Signal to do that. Equally, bad actors such as drug cartels may also feel safer using Signal. Their security against the US government lies in the fact that the US government shares their vulnerabilities. No one wants their secrets exposed.

I have long advocated for a "defense dominant" cybersecurity strategy. As long as smartphones are in the pocket of every government official, police officer, judge, CEO, and nuclear power plant operator—and now that they are being used for what the White House now calls calls  "sensitive," if not outright classified conversations among cabinet members—we need them to be as secure as possible. And that means no government-mandated backdoors.

We may find out more about how officials—including the vice president of the United States—came to be using Signal on what seem to be consumer-grade smartphones, in a apparent breach of the laws on government records. It’s unlikely that they really thought through the consequences of their actions.

Nonetheless, those consequences are real. Other governments, possibly including US allies, will now have much more incentive to break Signal’s security than they did in the past, and more incentive to hack US government smartphones than they did before March 24.

For just the same reason, the US government has urgent incentives to protect them.

This essay was originally published in Foreign Policy.

AIs as Trusted Third Parties

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/ais-as-trusted-third-parties.html

This is a truly fascinating paper: “Trusted Machine Learning Models Unlock Private Inference for Problems Currently Infeasible with Cryptography.” The basic idea is that AIs can act as trusted third parties:

Abstract: We often interact with untrusted parties. Prioritization of privacy can limit the effectiveness of these interactions, as achieving certain goals necessitates sharing private data. Traditionally, addressing this challenge has involved either seeking trusted intermediaries or constructing cryptographic protocols that restrict how much data is revealed, such as multi-party computations or zero-knowledge proofs. While significant advances have been made in scaling cryptographic approaches, they remain limited in terms of the size and complexity of applications they can be used for. In this paper, we argue that capable machine learning models can fulfill the role of a trusted third party, thus enabling secure computations for applications that were previously infeasible. In particular, we describe Trusted Capable Model Environments (TCMEs) as an alternative approach for scaling secure computation, where capable machine learning model(s) interact under input/output constraints, with explicit information flow control and explicit statelessness. This approach aims to achieve a balance between privacy and computational efficiency, enabling private inference where classical cryptographic solutions are currently infeasible. We describe a number of use cases that are enabled by TCME, and show that even some simple classic cryptographic problems can already be solved with TCME. Finally, we outline current limitations and discuss the path forward in implementing them.

When I was writing Applied Cryptography way back in 1993, I talked about human trusted third parties (TTPs). This research postulates that someday AIs could fulfill the role of a human TTP, with added benefits like (1) being able to audit their processing, and (2) being able to delete it and erase their knowledge when their work is done. And the possibilities are vast.

Here’s a TTP problem. Alice and Bob want to know whose income is greater, but don’t want to reveal their income to the other. (Assume that both Alice and Bob want the true answer, so neither has an incentive to lie.) A human TTP can solve that easily: Alice and Bob whisper their income to the TTP, who announces the answer. But now the human knows the data. There are cryptographic protocols that can solve this. But we can easily imagine more complicated questions that cryptography can’t solve. “Which of these two novel manuscripts has more sex scenes?” “Which of these two business plans is a riskier investment?” If Alice and Bob can agree on an AI model they both trust, they can feed the model the data, ask the question, get the answer, and then delete the model afterwards. And it’s reasonable for Alice and Bob to trust a model with questions like this. They can take the model into their own lab and test it a gazillion times until they are satisfied that it is fair, accurate, or whatever other properties they want.

The paper contains several examples where an AI TTP provides real value. This is still mostly science fiction today, but it’s a fascinating thought experiment.

Announcing the AWS CDK L2 Construct for Amazon Cognito Identity Pools

Post Syndicated from Adam Keller original https://aws.amazon.com/blogs/devops/announcing-the-aws-cdk-l2-construct-for-amazon-cognito-identity-pools/

Today we’re announcing the general availability (GA) of the new Amazon Cognito Identity Pool Level 2 (L2) construct in the AWS Cloud Development Kit (AWS CDK). This construct simplifies the creation and management of identity pools, permissions, and provider integrations by providing intent-based APIs that help users securely manage their authenticated and unauthenticated (guest) users across multiple identity providers (such as Amazon Cognito user pools, social providers like Facebook or Google, OpenID Connect, and more).

Background

The AWS CDK is an open-source software development framework that allows you to define cloud infrastructure using familiar programming languages, such as TypeScript, Python, Java, C#, and Go. The CDK provides various levels of abstraction through Constructs, which are reusable cloud components. Constructs come in three levels:

  • L1 constructs: Lowest level of constructs that are automatically generated from AWS CloudFormation resource specifications and offer no abstraction. They provide a one to one mapping to CloudFormation and can be verbose.
  • L2 constructs: Curated, high level abstractions that provide sensible defaults and reduce boilerplate code and glue logic with intuitive, intent-based APIs, making infrastructure provisioning more straightforward.
  • L3 constructs: Opinionated patterns that encapsulate multiple resources for a specific use case (for example, an entire web application stack).

Previously, developers who wanted to create Cognito Identity Pools in their CDK applications often had to work directly with L1 CloudFormation resources (for example, CfnIdentityPool and CfnIdentityPoolRoleAttachment). This led to verbose code, manual IAM role handling, and less intuitive support for multiple identity providers. The developer was responsible for all of the glue logic required when connecting Identity Pools to other AWS resources , creating IAM roles and policies and provider references on your own, which introduced more complexity.

The new AWS CDK Cognito Identity Pool L2 construct provides the following out of the box:

  • An easy way to create and manage authenticated and unauthenticated roles and permissions.
  • Built-in support for a variety of identity providers, including social providers, Amazon Cognito user pools, OpenID Connect providers, and others.
  • A high level API that reduces the amount of code and complexity required to manage the lifecycle of your identity pool.

By using this new L2 construct, you can focus on developing your application rather than the intricacies of wiring up roles, trust relationships, and provider configurations.

Using the L2

Let’s walk through an example of creating a new Cognito Identity Pool. In addition to creating the Identity Pool, we will create a Amazon DynamoDB table and then we’ll show you how to grant different levels of access for authenticated and unauthenticated users.

Create the DynamoDB Table and Cognito Identity Pool

// Create an identity pool
const identityPool = new IdentityPool(this, 'MyIdentityPool', {
    identityPoolName: 'MyIdentityPoolName',
   // Enable unauthenticated identities, disabled by default, 
   // enabling here for demonstration purposes 
   allowUnauthenticatedIdentities: true
});

// Create a new DynamoDB table
const myTable = new TableV2(this, 'MyTable', {
    partitionKey: { name: 'id', type: AttributeType.STRING },
    billing: dynamodb.Billing.onDemand()
});
// Grant read/write access on the table to authenticated users
myTable.grantReadWriteData(identityPool.authenticatedRole);

// Grant read only access to unauthenticated (guest) users
myTable.grantReadData(identityPool.unauthenticatedRole);

Let’s highlight a few key points:

  1. Single Declaration: By declaring an IdentityPool construct, you automatically get a role for authenticated users and one for unauthenticated users; however, by default, the construct disables guest access and only allows authenticated users. To enable unathenticated identities (guest access), you can set the allowUnauthenticatedIdentities parameter to true.
  2. Role and Policy Creation: You don’t have to manually define policies and roles, attach them or configure trust relationships. The L2 construct sets all of this up for you.
  3. Providers: You can specify a variety of identity providers (e.g., Google, Facebook, Amazon, Twitter, OpenID Connect, or Cognito user pools) in the authenticationProviders property.
  4. Permissions: With the roles exposed (identityPool.authenticatedRole and identityPool.unauthenticatedRole), you can easily grant or restrict fine-grained AWS resource permissions.

Multiple Authentication Providers

When using multiple providers, pass in the relevant configuration details. For example, to enable sign-in via Facebook and Google, you can provide:

const identityPool = new IdentityPool(this, 'MyIdentityPool', {
  authenticationProviders: {
    facebook: { appId: 'your-facebook-app-id' },
    google: { clientId: 'your-google-client-id' },
  },
});

The L2 takes care of generating the correct roles, trust relationships, and identity provider references behind the scenes.

Considerations for Moving to the New Construct

  1. Upgrade Path: If you currently use the L1 resources (CfnIdentityPool, CfnIdentityPoolRoleAttachment, etc.), you can migrate to the L2 construct by replacing those L1 declarations with the new IdentityPool L2. Adjust any references to custom roles or attachments to leverage the provided authenticatedRole and unauthenticatedRole properties.
  2. Compatibility: Verify the version of your AWS CDK. This L2 is available in newer CDK releases (check the changelog for specifics).
  3. Customization: If you have very specific or advanced requirements, like custom IAM conditions or policy statements, you can still refine or override the default roles or attach custom policies using the roles exposed by the L2.
  4. Alpha to GA Changes: Verify any potential feature limitations or changes in the API from the alpha to stabilized (GA) versions of the construct.

Conclusion

We’re thrilled to introduce the AWS CDK Cognito Identity Pool L2 construct, which simplifies identity pool setup and management. By leveraging a higher level API, you reduce the complexity of configuring roles and providers for your application’s user base. Whether you’re supporting social logins, guest access, or both, this new construct empowers you to build secure and scalable applications more quickly.

We invite you to get started with the Cognito Identity Pool L2 construct in your AWS CDK projects. For more information and examples, visit the AWS CDK GitHub repository and the official AWS CDK documentation. Feedback is also very important to us, so please create an issue in GitHub for any bugs or feature requests. We look forward to seeing how this new construct helps you streamline your authentication workflows and deliver exceptional user experiences.

AI Data Poisoning

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/ai-data-poisoning.html

Cloudflare has a new feature—available to free users as well—that uses AI to generate random pages to feed to AI web crawlers:

Instead of simply blocking bots, Cloudflare’s new system lures them into a “maze” of realistic-looking but irrelevant pages, wasting the crawler’s computing resources. The approach is a notable shift from the standard block-and-defend strategy used by most website protection services. Cloudflare says blocking bots sometimes backfires because it alerts the crawler’s operators that they’ve been detected.

“When we detect unauthorized crawling, rather than blocking the request, we will link to a series of AI-generated pages that are convincing enough to entice a crawler to traverse them,” writes Cloudflare. “But while real looking, this content is not actually the content of the site we are protecting, so the crawler wastes time and resources.”

The company says the content served to bots is deliberately irrelevant to the website being crawled, but it is carefully sourced or generated using real scientific facts—­such as neutral information about biology, physics, or mathematics—­to avoid spreading misinformation (whether this approach effectively prevents misinformation, however, remains unproven).

It’s basically an AI-generated honeypot. And AI scraping is a growing problem:

The scale of AI crawling on the web appears substantial, according to Cloudflare’s data that lines up with anecdotal reports we’ve heard from sources. The company says that AI crawlers generate more than 50 billion requests to their network daily, amounting to nearly 1 percent of all web traffic they process. Many of these crawlers collect website data to train large language models without permission from site owners….

Presumably the crawlers will now have to up both their scraping stealth and their ability to filter out AI-generated content like this. Which means the honeypots will have to get better at detecting scrapers and more stealthy in their fake content. This arms race is likely to go back and forth, wasting a lot of energy in the process.

Report on Paragon Spyware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/report-on-paragon-spyware.html

Citizen Lab has a new report on Paragon’s spyware:

Key Findings:

  • Introducing Paragon Solutions. Paragon Solutions was founded in Israel in 2019 and sells spyware called Graphite. The company differentiates itself by claiming it has safeguards to prevent the kinds of spyware abuses that NSO Group and other vendors are notorious for.
  • Infrastructure Analysis of Paragon Spyware. Based on a tip from a collaborator, we mapped out server infrastructure that we attribute to Paragon’s Graphite spyware tool. We identified a subset of suspected Paragon deployments, including in Australia, Canada, Cyprus, Denmark, Israel, and Singapore.
  • Identifying a Possible Canadian Paragon Customer. Our investigation surfaced potential links between Paragon Solutions and the Canadian Ontario Provincial Police, and found evidence of a growing ecosystem of spyware capability among Ontario-based police services.
  • Helping WhatsApp Catch a Zero-Click. We shared our analysis of Paragon’s infrastructure with Meta, who told us that the details were pivotal to their ongoing investigation into Paragon. WhatsApp discovered and mitigated an active Paragon zero-click exploit, and later notified over 90 individuals who it believed were targeted, including civil society members in Italy.
  • Android Forensic Analysis: Italian Cluster. We forensically analyzed multiple Android phones belonging to Paragon targets in Italy (an acknowledged Paragon user) who were notified by WhatsApp. We found clear indications that spyware had been loaded into WhatsApp, as well as other apps on their devices.
  • A Related Case of iPhone Spyware in Italy. We analyzed the iPhone of an individual who worked closely with confirmed Android Paragon targets. This person received an Apple threat notification in November 2024, but no WhatsApp notification. Our analysis showed an attempt to infect the device with novel spyware in June 2024. We shared details with Apple, who confirmed they had patched the attack in iOS 18.
  • Other Surveillance Tech Deployed Against The Same Italian Cluster. We also note 2024 warnings sent by Meta to several individuals in the same organizational cluster, including a Paragon victim, suggesting the need for further scrutiny into other surveillance technology deployed against these individuals.

More Countries are Demanding Backdoors to Encrypted Apps

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/more-countries-are-demanding-back-doors-to-encrypted-apps.html

Last month, I wrote about the UK forcing Apple to break its Advanced Data Protection encryption in iCloud. More recently, both Sweden and France are contemplating mandating backdoors. Both initiatives are attempting to scare people into supporting backdoors, which are—of course—are terrible idea.

Also: “A Feminist Argument Against Weakening Encryption.”

Friday Squid Blogging: A New Explanation of Squid Camouflage

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/friday-squid-blogging-a-new-explanation-of-squid-camouflage.html

New research:

An associate professor of chemistry and chemical biology at Northeastern University, Deravi’s recently published paper in the Journal of Materials Chemistry C sheds new light on how squid use organs that essentially function as organic solar cells to help power their camouflage abilities.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

My Writings Are in the LibGen AI Training Corpus

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/my-writings-are-in-the-libgen-ai-training-corpus.html

The Atlantic has a search tool that allows you to search for specific works in the “LibGen” database of copyrighted works that Meta used to train its AI models. (The rest of the article is behind a paywall, but not the search tool.)

It’s impossible to know exactly which parts of LibGen Meta used to train its AI, and which parts it might have decided to exclude; this snapshot was taken in January 2025, after Meta is known to have accessed the database, so some titles here would not have been available to download.

Still…interesting.

Searching my name yields 199 results: all of my books in different versions, plus a bunch of shorter items.

Critical GitHub Attack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/critical-github-attack.html

This is serious:

A sophisticated cascading supply chain attack has compromised multiple GitHub Actions, exposing critical CI/CD secrets across tens of thousands of repositories. The attack, which originally targeted the widely used “tj-actions/changed-files” utility, is now believed to have originated from an earlier breach of the “reviewdog/action-setup@v1” GitHub Action, according to a report.

[…]

CISA confirmed the vulnerability has been patched in version 46.0.1.

Given that the utility is used by more than 23,000 GitHub repositories, the scale of potential impact has raised significant alarm throughout the developer community.

Enable single-sign-on for Amazon WorkMail with IAM Identity Center and Okta Universal Directory

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/enable-single-sign-on-for-amazon-workmail-with-iam-identity-center-and-okta-universal-directory/

Securing your business email is more critical than ever in today’s digital workplace. To help you protect your users and data in Amazon WorkMail (WorkMail), we regularly introduce security features that give organizations more control and protection for their business email. Thanks to the recently announced integration between WorkMail and AWS Identity and Access Management (IAM) Identity Center (IAM IdC), WorkMail users can now enjoy single sign-on (SSO) via compatible 3rd party external identity providers including Okta Universal Directory (Okta), Microsoft Entra ID, Google Workspace, JumpCloud, OneLogin, Ping Identity products and Active Directory.

This blog post explains the specific steps needed to integrate WorkMail with Okta via IAM IdC. WorkMail customers who use other 3rd party identity providers that are compatible with IdC will also find this post useful alongside the AWS documentation for their specific identity source. Alternatively, WorkMail organization administrators who do not use an external identity provider, but wish to enable multi-factor-authentication (MFA) for WorkMail viaIAM IdC will find guidance in a different blog post.

By integrating WorkMail with Okta via IAM IdC, users benefit from the security, convenience, and familiarity of SSO when accessing their WorkMail inbox and calendars via the WorkMail web-app. WorkMail organization administrators benefit from the security and efficiency of managing WorkMail user additions, modifications, or removals via the Okta admin tools. More detailed information about this integration can be found in the IAM IdC documentation as well as in the WorkMail documentation.

Introduction

Email remains a critical business communication tool, yet it is also one of the most targeted entry points for cyber threats. A single compromised email account can expose sensitive business data, damage an organization’s reputation, and serve as a gateway for further cyber attacks. As traditional username and password authentication becomes increasingly inadequate, organizations must adopt stronger access controls to protect their users and communications.

You can enhance your WorkMail organization’s security and simplify user authentication with SSO and a familiar login experience by integrating WorkMail with IAM IdC and Okta. This (and similar) integrations provide a more seamless authentication experience and helps administrators enforce consistent security policies across their organization.
The integration between WorkMail, IAM IdC and Okta supports these industry standards:

WorkMail authentication options

When you first set up WorkMail, you use the built-in user directory which relies upon standard username | password authentication for the WorkMail web browser client as well as popular desktop and mobile email clients such as Microsoft Outlook, Apple Mail and Thunderbird.

WorkMail standard username/password

By default, WorkMail uses username | password authentication

The integration between IAM Identity Center and Okta uses the SCIM protocol to provision and map user attributes in Okta to named attributes in IAM IdC. Once enabled, user and group information from Okta is automatically synchronized with IAM IdC. IAM IdC in turn uses the SAML protocol to provide Okta users with a familiar and convenient SSO experience.

After integrating IAM IdC with Okta, WorkMail uses:

  1. Okta SSO for users of the WorkMail web-app.
  2. Personal access tokens (PAT) for users of desktop &/or mobile email applications.
WorkMail uses Okta SSO or PATs

After integration with IdC and Okta, WorkMail uses SSO (web-app) and username | PAT (desktop/mobile) for authentication

Prerequisites for the WorkMail, IAM IdC and Okta integration

  • Admin access to an AWS account
    • You can evaluate the integration in this post for a limited period of time using an AWS Free Tier Account
  • Admin access to an Amazon WorkMail Organization
    • The integration uses the email domain that is configured as WorkMail’s default
  • Admin access to Amazon IAM Identity Center
    • Or admin access to the IdC organization account
  • Your WorkMail and IAM Identity Center must be in the same AWS region
  • IAM Role with the security credentials needed to deploy AWS infrastructure via the AWS CDK
  • Administrator access to a fully functional Okta Identity account populated with users and (optionally) group(s) that you want to integrate and synchronize with IAM IdC and WorkMail.
  • Access to the AWS Samples GitHub repository, where you’ll find sample code that deploys via AWS CDK. This code sample deploys a customizable AWS Lambda initially configured to perform user synchronization between IAM IdC and WorkMail every 15 minutes.
  • A source code editor such as Visual Studio Code with your AWS admin credentials.

High-level Steps

  1. Configure Identity Center (See our documentation for detailed information).
  2. Configure Okta Identity integration with IAM Identity Center. See this post for more information
  3. Provision and synchronize Okta’s Groups (or Okta Users) with IAM Identity Center
  4. Configure WorkMail to use Identity Center
  5. Deploy the AWS CDK sample project found in aws-samples in GitHub
  6. Test user access to WorkMail with and without Okta SSO (web-app) and Personal Access Token (desktop & mobile email clients)
  7. Notify WorkMail users of upcoming changes to login procedures.
  8. Switch WorkMail Authentication Mode to IAM IdC.

Detailed Configuration Guidance

The instructions that follow walk you through the steps needed to integrate your Okta system with IAM IdC. Once IAM IdC is synchronizing with Okta, you’ll integrate IAM IdC with WorkMail. This process will keep your WorkMail organization’s users and groups synchronized with Okta. Once fully enabled, your WorkMail users will use their Otka SSO credentials to access the WorkMail web-client or a username and unique Personal Access Tokens to access desktop &/or mobile email clients. Let’s get started!

Configure Okta integration with IAM Identity Center (these steps have been adapted from this blog post)

    1. Open the Okta admin landing page in a new browser (tab).

Okta admin landing page

    1. Click the Applications Section in the left menu.
    2. Click on Applications in the dropdown menu.
    3. Click Browse App Catalog.

Applications page.

    1. Type AWS IAM Identity Center in the search box.
    2. Click on the app that matches AWS IAM Identity Center.

AWS IAM Identity Center

    1. Click Add Integration to initiate the integration process.

Add Integration button

    1. Type a memorable name (like Workshop AWS IAM Identity Center) for the application label, and click Done.

Application Labe

    1. Click on the Sign On tab, scroll down to view SAML Signing Certificates.

    1. Click Actions to download the certificate to your local machine. Keep the Okta Admin dashboard Open, you will need the SAML information found here to configure IdC in the next section.

Configure AWS IAM IdC

  1. In a new browser window (or tab), open the IAM IdC console in the same region as your WorkMail Organization (we’re using us-east-1).
  2. If this is your first time accessing IAM IdC, you’ll be greeted with the IdC console home page prompting you to “Enable IAM Identity Center”. Click Enable.

Enable IAM Identity Center

  1. Check that you are in the correct region, click Enable (note – this will enable an Organization instance of IdC, which is recommended. If you want to use an Account instance of IdC, please see the documentation).

enable an Organization instance of IdC

  1. Once IdC has been enabled, scroll down to the IAM Identity Center setup section and click Confirm Identity Source.

  1. Click Actions, and select Change identity source from dropdown menu.

Change identity source

  1. Select External identity provider and click Next.

External identity provider

  1. Upload the SAML certificate you downloaded from Okta (above, step xx)
  2. Open the Okta dashboard browser/tab. Under the SAML 2.0 configuration, scroll down and expand > More details.
    • Copy the Sign on URL from Okta SAML and paste the URL into the IdP sign-in URL field in IdC.
    • Copy the Issuer URL from Okta SAML and paste the URL into the IdP sign-in URL field in IdC.
    • Click Next.
  1. Type ACCEPT in the confirmation text box & click Change identity source.

Change identity source

  1. Switch back to the IAM IdC console browser window/tab. On the Settings page, locate the Automatic provisioning information box, and then choose Enable. Leave this browser window/tab open as you’ll need it to copy the values for the SCIM endpoint and Access token into Okta shortly (note – IdC Automatic provisioning uses SCIM protocol to provision users from Okta).

IdC Automatic provisioning

  1. Return to the Okta admin dashboard (you should have left it open in another browser window or tab). Under IAM Identity Center applications, select the Workshop AWS IAM Identity Center and open the Provisioning tab.
  2. Under Integration, click Configure API Integration.

Configure API Integration

  1. Select the checkbox next to Enable API integration to enable provisioning.
  2. Refer to the IAM IcC console browser window/tab you left open and copy (from IdC) and paste (into Okta) the values for:
    • Base URL field – paste the IdC SCIM endpoint value (make sure there is no trailing forward slash at the end of the URL).
    • API Token field, enter the Access token value.
    • Import Groups should be checked
  1. Click Test API Credentials to verify the credentials entered are valid (the message AWS IAM Identity Center was verified successfully! should appear).

AWS IAM Identity Center was verified successfully

  1. Save.
  2. Under Settings, choose To App, click Edit and select Enable for Create Users, Update User Attributes and Deactivate Users. Click Save.

Update User Attributes and Deactivate Users

  1. In the Okta admin dashboard’s left-hand menu pane, click on Directory.
    • Choose Groups to see the list of existing groups.
    • Click on the Add Group button to create a new group called workmail_users.
    • Fill in the required details for the new group, including:
      • Group Name: Enter workmail_users for the group.
      • Group Description (optional): Provide a description for the group’s purpose (WorkMail_users).
    • Save the New Group
    • Reload the page to see the newly created group
    • Click Assign people
    • Add Okta users to the workmail_users group
    • Click Save
  1. In the Okta admin dashboard’s left-hand menu pane, click on Applications and open the AWS IAM Identity Center application.
  2. Click the Assignments tab, choose Assign, then choose Assign to people.
  3. Choose the Okta users that you want to have access to WorkMail via IAM Identity Center app.
  4. For each user, click Assign, review the user info, and click Save then Go Back
  5. When all Okta users for whom you want WorkMail users created/synced have been assigned, click Done to start the process of provisioning the users into IAM Identity Center.

provisioning the users into IAM Identity Center

  1. On the Assignments page, choose Assign, and then choose Assign to groups.
  2. Click the Okta group (workmail_users) that you want to have access to WorkMail via IAM Identity Center.
  3. Click Assign, review the selections, click Save and Go Back. Click Done. This starts the process of provisioning the users in the workmail_users group into IAM Identity Center.
  4. Choose the Push Groups tab.
  5. Choose the workmail_users group that contains all the users that you assigned to the IAM Identity Center app.
  6. If the group is not found in the list, choose the Find groups by name option by clicking (+)Push Groups Menu.
  7. Enter the group name ( workmail_users) that you created in the previous step and select it from the search results
  8. Click Save. The group status changes to “pushing” then “Active” (this can take several minutes), once the Okta workmail_users group and all its members have been pushed to IAM Identity Center.
  9. Return to the browser window/tab with the IAM Identity Center console.
  10. In the left navigation, select Groups (or Users) (you should see the Group (or users) list that was just populated by the Okta “push” action).

elect Groups (or Users)

Enable IAM Identity Center in Amazon WorkMail

  1. Open a new browser window (tab) to the WorkMail console in the same region as IdC, and open your WorkMail Organization.
  2. In WorkMail’s left navigation rail click Identity Center
  3. Click on Multi-factor authentication setup guide, Click Enable Identity Center, read the default configuration notice ,and click Enable

Enable Identity Center

  1. Under Identity Center Settings, click the Authentication mode tab and ensure it is set for WorkMail directory and Identity center (this is the default).
  2. This mode is needed for testing and to allow desktop & mobile email client users to retrieve their unique personal access tokens.
  3. Once the integration with IdC is successfully tested, and those WorkMail users who rely on desktop or mobile email clients for access have had the opportunity to login to the WorkMail web app to retrieve a PAT, you will change the Authentication mode to Identity center only.

Deploy the sample solution from GitHub

Solution prerequisites:

– AWS Account
– AWS IAM user with Administrator permissions
Python (> v3.x) and Pip fully installed and configured on your computer
AWS CLI (v2) installed and configured on your computer
AWS CDK (v2) installed and configured on your computer
Sample CDK project that creates and deploys an AWS Lambda in your AWS account to perform users synchronization between IAM IdC and WorkMail.

The instructions that follow guide you in deploying a sample solution for the AWS Samples Serverless-Mail repository that programmatically creates/syncs WorkMail users from IAM Identity Center using the AWS CDK CLI. The sample uses naming conventions used in this blog. For example, the Lambda only syncs those users found in the IdC Group named "workmail_users". If your IdC group has a different name, or you want to sync multiple IdC groups with WorkMail, you will need to modify the sample code before proceeding. (BE AWARE: The sample code base is an Open Source starter project designed to provide a demonstration and a base to start from for specific use cases. It should not be considered fully Production-ready, nor should it be deployed in a production environment. Refer to the README.md and License.md for more information.)

  1. Clone the sample project to your computer (git clone https://github.com/aws-samples/serverless-mail/tree/main/idc_okta-workmail). CD into the ‘idc_okta-workmail‘ directory.
  2. Create a virtual environment for packaging in Python (Docker must already be running locally) with python3 -m venv .venv
  3. Activate the virtual environment with source .venv/bin/activate
  4. Make sure cdk.json references the correct path to Python (by default cdk.json refers to .venv/bin/python app.py). If you need to locate Python, run the which python command.
  5. Install the project dependencies with pip3 install -r requirements.txt
  6. Check the AWS CLI local credentials and region with aws sts get-caller-identity . If you need to change any parameter, run aws configure
  7. Prepare the `app.py` file by running python3 get-my-variables.py  . The ‘get-my-variables.py’ script fetches the necessary variables from your AWS account and create the `app.py` file needed by the CDK. You may want to review the auto-generated `app.py` file for accuracy, especially if the AWS account has been used for other IdC or WorkMail related projects. The app.py file requires the following account variables:
    • AWS accountId
    • AWS Region – the region must be the same for IdC and WorkMail.
    • IDENTITYSTORE_ID – – found in the Identity Center console under settings or via the AWS CLI aws identitystore list-groups --identity-store-id {identity_store_id}
    • IDENTITY_CENTER_INSTANCE_ARN – found in the Identity Center console under settings or via the AWS CLI aws sso-admin list-instances
    • IDENTITY_CENTER_APPLICATION_ARN – found in the Identity Center console under Applications or via the AWS CLI aws sso-admin list-applications --instance-arn {instance_arn}`
    • WORKMAIL_ORGANIZATION_ID – found in the WorkMail console under Organizations or via the AWS CLI aws workmail list-organizations
    • OKTA_GROUP_ID_TO_ASSIGN_TO_WORKMAIL – found in the Identity Center console under Groups > General Information or via the AWS CLI aws identitystore list-groups --identity-store-id {identity_store_id}
  8. Bootstrap the package (this step may take several minutes to complete) with cdk bootstrap
  9. Synthesize the package (this step may take several minutes to complete) with cdk synthesize
  10. Deploy your package (this step may take several minutes to complete) with cdk deploy and follow the prompts in the AWS CDK CLI.
  11. Once deployment to your AWS account starts, you can view the deployment status in the CloudFormation console.

Confirm WorkMail Authentication mode

WorkMail’s default Authentication mode should be set to WorkMail directory and Identity center. Don’t change this yet. This mode will allow WorkMail web-app users to continue to login to the WorkMail client directly, without Okta SSO. WorkMail’s Personal access token configuration default is set to active, and token lifespan set to 365 days. You can change this if your security needs differ from the default. PATs are used by desktop and mobile email clients to login to WorkMail. Leaving WorkMail’s default Authentication mode set to WorkMail directory allows desktop and mobile email clients to continue to login to the WorkMail with their username and password, without yet requiring a PAT instead of password.

Conduct a few spot tests to verify WorkMail web-app users can properly access their WorkMail accounts via:

  1. The Amazon WorkMail web application URL (found on the WorkMail organization page)

Webmail login link

  1. Your organization’s unique AWS access portal URL (found on the setting page of the IAM IdC dashboard).

  1. This will open a new browser tab that redirects to the Okta user login page.

Okta user login page

  1. Once user has authenticated, this page will redirect to the AWS access portal with linked application tiles to all of the AWS applications that have been integrated with IAM Identity Center.

AWS access portal with linked application tiles

  1. Click on the WorkMail logo, and the WorkMail web-app will load.

WorkMail web-app

  1. Desktop or mobile email software users need to create a WorkMail Personal Access Token (PAT) to access WorkMail. These users must retrieve their own PATs after logging into the WorkMail web-client. Open the Webmail login link found on the WorkMail Organization page under User Login

Webmail login link

  1. In the WorkMail web-app,
    1. click the settings gear (in top right)
    2. Click Personal Access token and enter a token name (i.e. desktop-thunderbird-pat)
    3. Click Create token.
    4. Click Create token.
    5. Copy the token value (this is the only time you can retrieve this token value).
  2. Open your desktop or mobile email software, enter your username and your PAT (the PAT replaces your existing user password).

WorkMail web-app

  1. In settings, click Personal Access token and Create token
  2. Enter a token name (typically the device on which you’ll use this PAT) and select create token.
  3. Copy the token value (this is the only time you can retrieve this token value).
  4. Open your desktop or mobile email software, enter your username and your PAT (the PAT replaces your existing user password), and test your new login (username | PAT).

enter your username and your PAT

Notify your WorkMail users of upcoming changes to login procedures

Once you have tested the integration between WorkMail and IAM Identity Center with a few test users, you should prepare your WorkMail users for the increased login security. For example, you could send them an email that explains:

  • The organization is adding an additional login security step to help protect their inboxes.
  • Inform them that they should anticipate an email from the AWS IAM Identity Center with info about the upcoming implementation of MFA for web-app users and PATs for desktop and mobile client users.
  • Users should accept the invitation and create a new password for the AWS IAM Identity Center.
  • Inform them that once WorkMail MFA is enabled, all WorkMail web-app users will be required to use their username, password and MFA.
  • Inform them that once WorkMail PATs are enabled, all WorkMail desktop and mobile email client users will need to login to the WorkMail web client (with MFA) via the AWS access portal URL, create one PAT per software client (the same PAT can not be used on desktop and mobile). They then must update their desktop or mobile email software to use their username and PAT, instead of their current password. Explain that the PAT is now their email client application password and their personal desktop or mobile email software passwords will no longer work.
  • Provide users with a way to request support.

Switch WorkMail Authentication Mode to Identity Center only

  1. Once you are satisfied that your WorkMail users have incorporated Okta SSO and/or PATs into their WorkMail login routines, the WorkMail administrator should disable the WorkMail directory Authentication mode found in the WorkMail console under Organization > Identity Center.

disable the WorkMail directory Authentication mode

  1. Optional – Ask several trusted users to test their ability to login to WorkMail web app via Okta credentials.

Congratulations, your WorkMail organization’s authentication is now being managed by IAM Identity Center and your external identity provider, Okta.

Conclusion

By integrating IAM Identity Center with Okta Identity and WorkMail, you can provide your users with the convenience of Okta SSO for the WorkMail web-app. This allows your organization to improve it’s email security posture, better safeguard sensitive communications and protect you WorkMail organization against unauthorized access. Furthermore, this integration reduces admin overhead as user access to WorkMail is allowed, or revoked via the Okta administration dashboard.

Take control of your email communications today with Amazon WorkMail:

  1. Visit the WorkMail Console to begin configuration.
  2. Enable IAM Identity Center Integration with Okta and WorkMail.
  3. Connect your WorkMail organization to centralized access management.
  4. Configure WorkMail to require:
    1. Okta SSO – Adds an extra layer of security for web-app users.
    2. Personal Access Tokens (PAT) – Add an extra layer of security for desktop and mobile client access.

Need guidance? Check out our technical documentation. Contact your AWS account team.

To help keep your WorkMail organization secure, we recommend:

  • Regularly reviewing your WorkMail audit logs for unexpected activity.
  • Monitoring for unauthorized access attempts.
  • Staying informed about the latest security practices.

Dive deeper into WorkMail security with these resources:

Join the Conversation:
Connect with other administrators and security professionals on the AWS re:Post community to share insights and learn best practices.

Is Security Human Factors Research Skewed Towards Western Ideas and Habits?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/is-security-human-factors-research-skewed-towards-western-ideas-and-habits.html

Really interesting research: “How WEIRD is Usable Privacy and Security Research?” by Ayako A. Hasegawa Daisuke Inoue, and Mitsuaki Akiyama:

Abstract: In human factor fields such as human-computer interaction (HCI) and psychology, researchers have been concerned that participants mostly come from WEIRD (Western, Educated, Industrialized, Rich, and Democratic) countries. This WEIRD skew may hinder understanding of diverse populations and their cultural differences. The usable privacy and security (UPS) field has inherited many research methodologies from research on human factor fields. We conducted a literature review to understand the extent to which participant samples in UPS papers were from WEIRD countries and the characteristics of the methodologies and research topics in each user study recruiting Western or non-Western participants. We found that the skew toward WEIRD countries in UPS is greater than that in HCI. Geographic and linguistic barriers in the study methods and recruitment methods may cause researchers to conduct user studies locally. In addition, many papers did not report participant demographics, which could hinder the replication of the reported studies, leading to low reproducibility. To improve geographic diversity, we provide the suggestions including facilitate replication studies, address geographic and linguistic issues of study/recruitment methods, and facilitate research on the topics for non-WEIRD populations.

The moral may be that human factors and usability needs to be localized.

Improvements in Brute Force Attacks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/improvements-in-brute-force-attacks.html

New paper: “GPU Assisted Brute Force Cryptanalysis of GPRS, GSM, RFID, and TETRA: Brute Force Cryptanalysis of KASUMI, SPECK, and TEA3.”

Abstract: Key lengths in symmetric cryptography are determined with respect to the brute force attacks with current technology. While nowadays at least 128-bit keys are recommended, there are many standards and real-world applications that use shorter keys. In order to estimate the actual threat imposed by using those short keys, precise estimates for attacks are crucial.

In this work we provide optimized implementations of several widely used algorithms on GPUs, leading to interesting insights on the cost of brute force attacks on several real-word applications.

In particular, we optimize KASUMI (used in GPRS/GSM),SPECK (used in RFID communication), andTEA3 (used in TETRA). Our best optimizations allow us to try 235.72, 236.72, and 234.71 keys per second on a single RTX 4090 GPU. Those results improve upon previous results significantly, e.g. our KASUMI implementation is more than 15 times faster than the optimizations given in the CRYPTO’24 paper [ACC+24] improving the main results of that paper by the same factor.

With these optimizations, in order to break GPRS/GSM, RFID, and TETRA communications in a year, one needs around 11.22 billion, and 1.36 million RTX 4090GPUs, respectively.

For KASUMI, the time-memory trade-off attacks of [ACC+24] can be performed with142 RTX 4090 GPUs instead of 2400 RTX 3090 GPUs or, when the same amount of GPUs are used, their table creation time can be reduced to 20.6 days from 348 days,crucial improvements for real world cryptanalytic tasks.

Attacks always get better; they never get worse. None of these is practical yet, and they might never be. But there are certainly more optimizations to come.

Friday Squid Blogging: SQUID Band

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/friday-squid-blogging-squid-band.html

A bagpipe and drum band:

SQUID transforms traditional Bagpipe and Drum Band entertainment into a multi-sensory rush of excitement, featuring high energy bagpipes, pop music influences and visually stunning percussion!

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.