Post Syndicated from jake original https://lwn.net/Articles/1105913/
Videos from the 2026 X.Org Developers Conference (XDC) are now available on YouTube. XDC was held in Toronto, Ontario, Canada September 28-30.
Post Syndicated from jake original https://lwn.net/Articles/1105913/
Videos from the 2026 X.Org Developers Conference (XDC) are now available on YouTube. XDC was held in Toronto, Ontario, Canada September 28-30.
Post Syndicated from Ritesh Sinha original https://aws.amazon.com/blogs/big-data/store-and-process-large-strings-in-amazon-redshift-super-columns/
Storing large semi-structured data such as JSON and arrays in a data warehouse often means splitting or truncating your data. Amazon Redshift removes this with the SUPER data type and PartiQL language so you can ingest, store, transform, and analyze semi-structured data such as weblogs and sensor data at scale. When you turn on large string support, SUPER supports individual strings up to 16 million bytes and processes strings beyond the 65,535 bytes VARCHAR limit in memory. SUPER also works in case-insensitive databases.
In this post, we walk you through three key SUPER data type enhancements that simplify semi-structured data workflows and reduce common migration challenges.
To implement this solution, you need the following prerequisites:
Yes attached to your Amazon Redshift data warehouse. For Amazon Redshift Serverless, set the same parameter in your workgroup configuration. For details, see Behavior changes in Amazon Redshift.The SUPER data type helps you process and query semi-structured or nested data. This includes web logs, industrial Internet of Things (IoT) data from machines and equipment, sensor data, genomics data, and more.
The following diagram illustrates the data flow. It shows how data is generated, collected, and stored in Amazon Redshift as the SUPER data type:
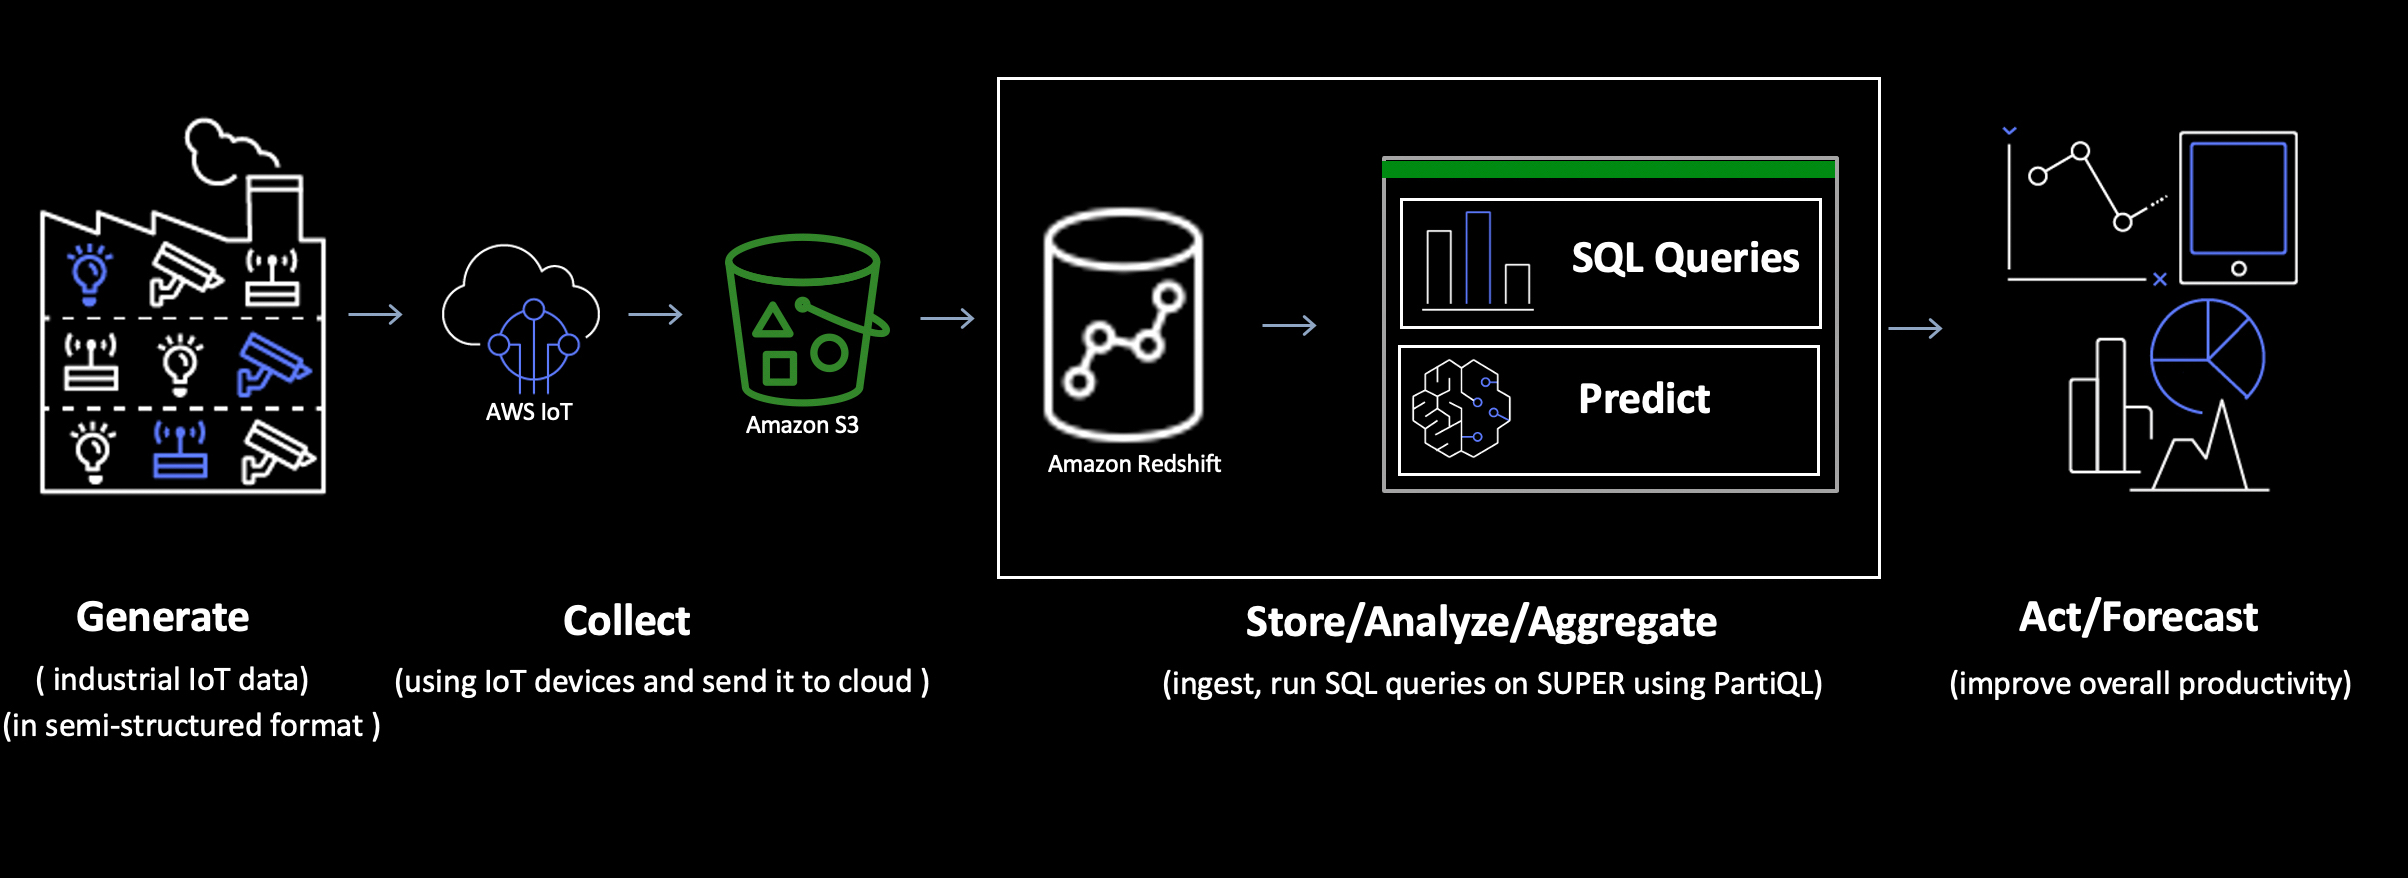 Figure 1: Use case overview flow
The challenge
Today, organizations need to store and analyze large semi-structured documents such as detailed customer profiles, comprehensive transaction records, IoT sensor data, and complex event logs.
The solution
Amazon Redshift now supports storing objects up to 16 million bytes in SUPER data type columns. When you turn on large string support, individual strings within SUPER columns now support up to 16 million bytes. You can store complete legal documents, detailed product catalogs with formatting intact, full application logs, extensive customer interaction histories, and entire articles, with no splitting or truncating your data.
To follow along with this solution, complete the following:
Turn on large string support. Create a parameter group (or edit an existing one), set enable_large_strings_opt_in to Yes, and attach the parameter group to your data warehouse. For a provisioned cluster, reboot the cluster to apply the change. For Amazon Redshift Serverless, set the enable_large_strings_opt_in configuration parameter on your workgroup instead, because Serverless doesn’t use parameter groups.
Confirm the setting:
Create the orders table:
Load large JSON documents (up to 16 million bytes) with strings > 65535 bytes into orders table using COPY:
Select data from orders table:
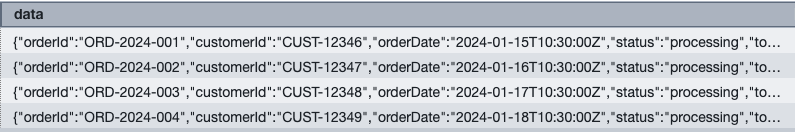
Figure 2: Orders result set
The following query extracts specific fields from nested JSON documents stored in the data SUPER column of the orders table. Before querying, you set enable_case_sensitive_super_attribute to true, so you can reference camelCase attribute names such as orderId and shippingAddress without double quotation marks. The SELECT clause retrieves order and customer identifiers, shipping address details, and a description field that supports up to 16 million bytes of text, along with its character length. The WHERE clause returns only orders with a status of ‘processing‘.
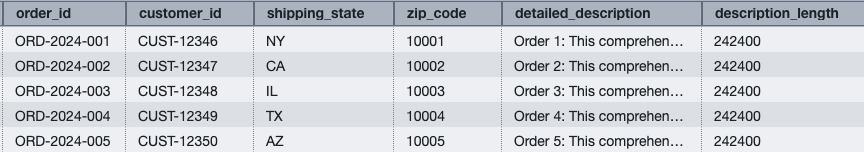
Figure 3: Large string result set
The challenge
Running string operations on large semi-structured data has trade-offs such as either truncating at 65,535 bytes and losing critical information, or disk spills impacting query performance. Standard SQL string functions like substring extraction, pattern matching, and text transformations become impractical when your data exceeds these limits. This leaves you with incomplete analysis or unacceptable latency.
The solution
When you set enable_large_strings_opt_in to Yes, Amazon Redshift supports in-memory string function operations on SUPER data that exceed the 65,535 bytes VARCHAR limit. By casting SUPER values to VARCHAR within string functions, Amazon Redshift processes the full string in memory without truncation to upper limit of 16 million bytes. Table columns defined as VARCHAR(MAX) stay at 65,535 bytes. The larger limit applies to in-memory operations such as CAST expressions, views, UDFs, and stored procedures.
How it works:
Problem scenario (causes error):
Run the following query to retrieve customer IDs from the orders table and convert them to lowercase; you will get an error.
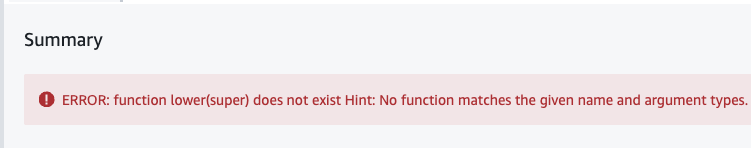
Figure 4: Output without using CAST
Solution (works without truncation):
Run the following query to retrieve customer IDs from the orders table, cast them to VARCHAR and convert them to lowercase, query executes successfully.
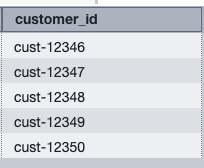
Figure 5: Query result showing customer IDs
Next, let’s see how the SUPER data type accommodates string values larger than 65,535 bytes. We use the LISTAGG and LEN functions to test this enhancement. The LISTAGG window function orders rows for each group according to the ORDER BY expression, then concatenates the values into a single string. The LEN function returns the length of the specified string as the number of characters. This operation wasn’t possible with the previous 65,535 bytes limit.
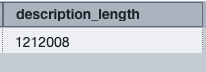
Figure 6: Query result showing description length
The output shows a string length of 1,212,008 characters. This demonstrates that SUPER can now handle strings beyond the previous 65,535-byte limit. If the output of LISTAGG exceeds the 65,535-byte limit of a VARCHAR column, you can store the result in a SUPER column, which supports up to 16 million bytes.
With large string support turned on, VARCHAR(MAX) in a view resolves to VARCHAR(16000000), so the view can return full-length strings. Because views keep the case settings from their creation, run SET first, then create the view after you turn on the setting:
Views that you created before you turned on the setting stay capped at 65,535 bytes until you recreate them. For more information, see Behavior changes in Amazon Redshift.
The challenge
Organizations migrating from legacy data warehouses to Amazon Redshift face a critical decision regarding database collation. Your data warehouse operates with case-insensitive string comparisons by default, and maintaining this behavior is essential for application compatibility. However, until recently, SUPER data types were only supported in Amazon Redshift databases with case-sensitive collation, creating a migration barrier. If you created Amazon Redshift case-insensitive databases to ease your migration process (avoiding the extensive testing required for case-sensitive conversion), you couldn’t use the SUPER data type for ingesting and querying semi-structured data such as JSON and arrays in Amazon Redshift native and data lake tables.
The solution
Amazon Redshift announced support for SUPER data types in databases with case-insensitive collation, which has the following benefits:
Amazon Redshift native table with SUPER data type
SET enable_case_sensitive_super_attribute TO true;
 SELECT * FROM customer_data;

Figure 7: Result set of customer_data
order_history array column using PartiQL. Figure 8: Result set of customer_data using partiql
 Figure 9: Result set of customer_data and order_history using partiql
In this example, the order_history column uses COLLATE case_sensitive, which overrides the case-insensitive default of the database for that column. To compare both behaviors, you can also use the COLLATE function in a WHERE clause.
Query nested data type on data lake
datalake_withsuper_datatype. For instructions on how to create the AWS Glue database, see Creating databases.datalake_withsuper_datatype in crawler. For instructions on how to create a crawler, see Tutorial: Adding an AWS Glue crawler.custdb_case_insensitive.
Figure 10: Result set of customer_profile using glue data catlog
In this section, we discuss the best practices that you can follow while using SUPER data type in Amazon Redshift.
Set the following session setting before you query SUPER columns for accurate field name matching. With this setting on, reference field names without double quotation marks:
Without this setting, Amazon Redshift converts unquoted field names to lowercase. When your JSON contains orderId but Amazon Redshift searches for orderid, queries return NULL values instead of your data.
Example: Impact of enabling case sensitivity
The following example shows the difference in query results with and without case sensitivity enabled:
Always cast SUPER values to appropriate data types for better performance and accuracy:
Explicit casting eliminates ambiguity and improves query performance by helping Amazon Redshift optimize execution plans.
Promote frequently queried fields
Extract commonly accessed SUPER attributes to regular columns for faster queries:
Create materialized views for complex queries
Turn on enable_case_sensitive_super_attribute, then build materialized views for queries you run repeatedly:
Use AWS Schema Conversion Tool (AWS SCT) to convert your schema automatically, then configure case sensitivity for SUPER columns.
Set user-level configuration
Enable case sensitivity for all of a single user’s sessions:
Test both column types
Verify that regular columns maintain case-insensitive behavior:
Confirm that SUPER columns enforce case sensitivity:
Update application queries:
Modify your application code to use correct case and explicit casting for all SUPER column attributes. This ensures consistent results and prevents NULL values from case mismatches.
Keep the enable_large_strings_opt_in setting the same on data sharing producer and consumer data warehouses.
Recreate existing views, UDFs, and stored procedures after you turn on the setting. They stay capped at 65,535 bytes until you recreate them.
After you set the parameter to Yes or No, you can’t reset it to the default value.
For more information about best practices for working with semi-structured data types, see documentation.
The enhanced SUPER data type of Amazon Redshift solves the previously mentioned critical challenges that you face when working with semi-structured data. This post showed you how to turn on large string support, store individual strings in JSON documents up to 16 million bytes, perform string operations without truncation errors, and maintain case-insensitive compatibility during database migrations.
With SUPER, you can handle comprehensive data objects including legal contracts, product catalogs, customer profiles, and IoT sensor readings without breaking them into smaller pieces.
You can also cast SUPER values to VARCHAR and run pattern matching, text manipulation, and data cleansing operations directly on SUPER columns, and remove the truncation errors that previously blocked your analysis workflows.
Start implementing these capabilities in your environment with the following steps:
Post Syndicated from daroc original https://lwn.net/Articles/1103190/
When a computer hibernates, the kernel writes the contents of memory to disk and
then shuts the system down. Resuming from hibernation involves reading that data
back into memory, and then having the kernel pick up where it left off.
Unfortunately, the kernel does not have
any way to know that the data it is reading back has not been tampered with,
which is why lockdown, an optional kernel
feature that attempts to prevent modifications to the running kernel, disables hibernation.
Matthew Garrett, who has been working on lockdown for many years, has shared
a patch set that aims to fix this problem. His solution must also protect
against downgrade attacks (where an attacker reboots the computer with an older
kernel version to bypass new protections), which complicates the implementation.
Post Syndicated from jzb original https://lwn.net/Articles/1105902/
Hot on the heels of the previous
two stable kernels, Greg Kroah-Hartman has announced the release of the 7.3.3, 6.18.62,
6.12.116, 6.6.162, 6.1.192,
5.15.225, and 5.10.274 stable kernels. Each one only contains
fixes for three use-after-free vulnerabilities announced today by the Xen
security team.
Two of the vulnerabilities could allow an attacker to DoS the
entire Xen host machine with possible information leakage (CVE-2026-100080,
CVE-2026-100082),
and one may allow privilege escalation as well as a DoS of the host machine (CVE-2026-100081). Users
should, of course, upgrade if they are using Xen.
Post Syndicated from Home Assistant original https://www.youtube.com/shorts/MPIgVawiXas
Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/your-guide-to-the-developer-tools-track-at-aws-reinvent-2026/
AWS re:Invent 2026 is almost here, and if you’re a developer, the Developer Tools (DVT) track is where you’ll want to spend your week. This year is all about agentic development, from multi-agent workflows to autonomous agents that keep working while you sleep. And CI/CD, Infrastructure as Code, and full-stack development are still well represented. Here’s your essential guide to the week.
AWS re:Invent is a learning conference, and the Developer Tools track has 46 unique sessions waiting for you. Choose from breakouts, chalk talks, workshops, builders sessions, code talks, and lightning talks. Roughly three-quarters of the slots are interactive, so bring your questions and maybe your laptop. You can find the complete schedule in the re:Invent 2026 catalog. These are the sessions I would check first.
Want to get hands-on? Try DVT406: Make the agent code while you sleep, a 400-level workshop on autonomous development with the Kiro CLI, or DVT207: Learn new AI development skills with Kiro, a builders session that’s a great place to start if you’re new to Kiro. Both repeat during the week, so you’ll have more than one chance to get a seat.
Start your journey at Kiro Galaxy Run in Caesars Forum. Strap into an immersive VR space mission that goes horribly off course, and use Kiro and its agents to get your crew home. Stick around for live demos at the Kiro kiosk, grab a Builder Quest stamp, and pick up some Kiro swag on your way out.
Visit the AWS Village in the Expo at the Venetian to talk with me and other experts at the Kiro kiosk. See Kiro in action, ask your toughest questions, and pick up stickers and Kiro credits.
Swing by the Builder Zone to explore the Builders Fair, Agent Forge, and open source areas, along with Kiro demos. This is also where you can sign up for Builder Quest and collect stamps to earn credits and prizes.
Learn at your own pace in the Ctrl+Alt+Ship labs at the Venetian Content Hub. Kiro has two labs: a 200-level lab to get you started with the Kiro IDE, and a 400-level lab on autonomous development.
Make the most of re:Invent by attending these sessions, finding us at the AWS Village and Builder Zone, and taking on Kiro Galaxy Run. Whether you’re focused on CI/CD, infrastructure as code, full-stack development, or the next wave of agentic development, the Developer Tools track has something for you. If you are already registered, I look forward to seeing you in Las Vegas. If you are not registered, there is still time to register for re:Invent 2026.
Post Syndicated from Ronald Teijeira Fernandez original https://aws.amazon.com/blogs/devops/run-maestro-tests-on-real-android-devices-using-aws-device-farm/
ManoMano is a European online marketplace for home improvement and gardening products. Their mobile engineering team builds a React Native application that serves millions of customers across Europe. To verify app quality across a wide range of Android devices, ManoMano adopted Maestro for end-to-end (E2E) testing and needed a way to run these tests at scale on real hardware. This post shares how they solved that challenge using AWS Device Farm.
In this post, you learn how to run Maestro mobile UI tests on real Android devices using AWS Device Farm. Maestro is a mobile UI testing framework that uses a declarative YAML syntax to describe test flows. By using the custom test environment in AWS Device Farm, you can install and run Maestro flows on real physical devices in the cloud.
This post is for mobile developers and Quality Assurance (QA) engineers who use Maestro for E2E testing and want to scale their test suites across real Android devices with different brands, screen sizes, and OS versions.
Many teams that adopt React Native prefer Maestro for its YAML-based simplicity and reliable mobile testing capabilities. With the custom test environment feature in AWS Device Farm, you can run any framework that operates over Android Debug Bridge (ADB), including Maestro. This post shows you how to set it up end to end.
AWS Device Farm is a fully managed app testing service that you can use to test your Android and iOS apps on physical devices in the AWS Cloud. It provides officially supported frameworks (Appium, Espresso, and XCTest) with all dependencies and setup pre-configured. It also offers custom test environments that give you full control over the test host. This means you can install and run any framework that operates over ADB, including Maestro. The custom environment provides the following capabilities:
With these capabilities, you can install the Maestro CLI and, if needed, its primary dependency (for example, Java 21) on the test host. You then run your YAML-based test flows against the connected device, the same way you run them locally.
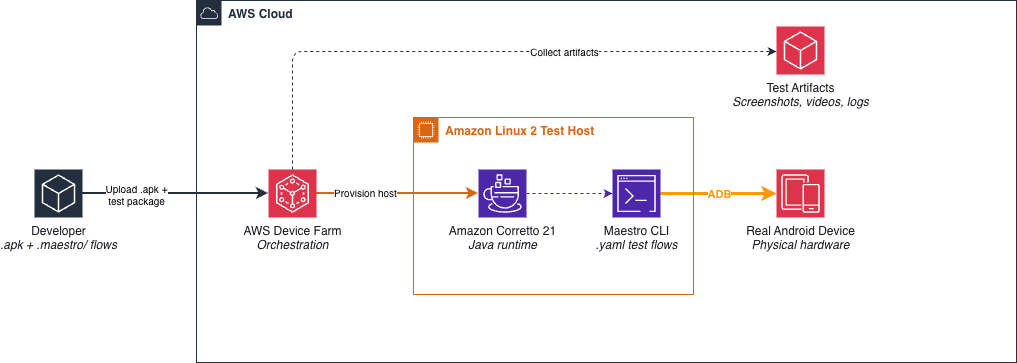
Figure 1: Solution architecture
The solution uses the following workflow:
.yaml test flows.$DEVICEFARM_LOG_DIR directory.Note: This approach currently supports Android devices only. As of 2026, Maestro iOS support is optimized for simulators and does not work with the real physical iOS devices that AWS Device Farm provides (as indicated in the Maestro documentation).
To complete this walkthrough, you must have the following:
dev.mobile.maestro) for uploading as Extra Apps in AWS Device Farm. After running Maestro locally at least once on a connected device, you can extract the installed APKs using adb shell pm path dev.mobile.maestro.Complete the following steps to configure and run Maestro tests on AWS Device Farm.
Build your React Native (or native Android) application as an .apk file. Use a release build or a dedicated test build with animations disabled to reduce test flakiness.
AWS Device Farm expects a test package in .zip format. Use this zip file as a carrier for your Maestro .yaml flows. The following example shows a typical test directory structure:
Run the following command to package the directory into a zip file:
Upload this zip file to AWS Device Farm as your test package. AWS Device Farm extracts it to $DEVICEFARM_TEST_PACKAGE_PATH, which makes your flows accessible during test execution.
In the AWS Device Farm Console, create a test run with the following configuration:
testspec.yml with the custom configuration in Step 4.dev.mobile.maestro). AWS Device Farm installs these on the device before the test begins to help you maintain compatibility with restrictive Android skins.The following test spec instructs AWS Device Farm to download Amazon Corretto 21, install the Maestro CLI, and run your test flows.
In the following code, replace {YOUR_APP_ID} with your application package ID (for example, com.example.myapp). You can find this in your application’s AndroidManifest.xml or by running adb shell pm list packages | grep <your-app-keyword>.
For more information, see Custom test environments in AWS Device Farm.
The test spec uses the following AWS Device Farm environment variables:
$DEVICEFARM_TEST_PACKAGE_PATH: The path where AWS Device Farm extracts your uploaded test package (zip file).$DEVICEFARM_LOG_DIR: The default directory for storing artifacts. AWS Device Farm collects files from this directory after the run.$DEVICEFARM_APP_PATH: The path to your uploaded .apk file on the test host.$DEVICEFARM_DEVICE_NAME: The unique device identifier (UDID) of the device under test.$DEVICEFARM_DEVICE_OS_VERSION: The Android OS version running on the device.After the test run completes, AWS Device Farm displays results organized into three suites:
pre_test phases, including Amazon Corretto and Maestro installation.maestro test command, with pass/fail status for each flow.post_test phase output and device cleanup.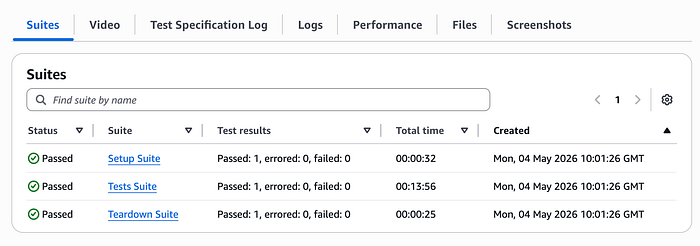
Figure 2: AWS Device Farm test run results showing the Setup, Tests, and Teardown suites
In the Test Specification Log, you can view the live console output. The following example shows typical output during a test run:
To download detailed results, including screenshots and video recordings, open the Files tab and choose Customer Artifacts. For more information, see Downloading artifacts in a custom test environment.
Maestro requires a driver app to be installed on the device under test. On devices with restrictive Android skins (such as Xiaomi MIUI and Oppo ColorOS, which are common in the AWS Device Farm device pool), the operating system blocks USB installations. Installation proceeds only after a user accepts a security prompt, as displayed in Figure 3.
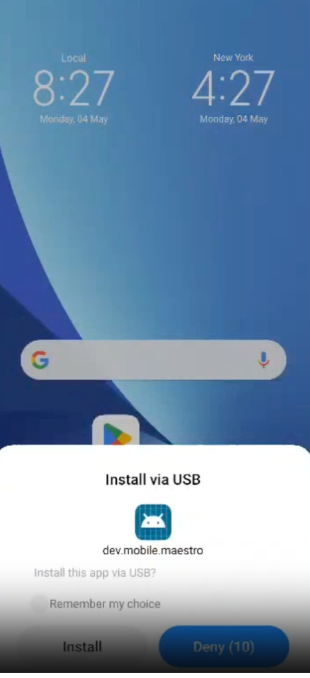
Figure 3: MIUI installation permission dialog
The way to address this scenario is by pre-installing the Maestro driver APKs as Extra Apps in the AWS Device Farm Console. When you upload the Maestro APKs alongside your application, AWS Device Farm installs them on the device before the test begins. You can then grant the necessary background permissions through ADB using appops commands in the pre_test phase:
These commands tell the OS to trust the Maestro driver app, allowing it to run in the background and start activities without user interaction. This approach removes the need for the UI watcher script and helps make sure that Maestro can start driving your application when the test begins.
The following recommendations are based on the AWS Device Farm best practices for custom test environments:
$DEVICEFARM_TEST_PACKAGE_PATH, $DEVICEFARM_LOG_DIR, and other variables that help maintain consistent behavior across test hosts.$DEVICEFARM_LOG_DIR: Use the --test-output-dir flag to write Maestro output to this directory. AWS Device Farm collects artifacts stored here automatically.pre_test phase.--include-tags or --exclude-tags to run subsets of your test suite, such as smoke tests compared with full regression.You can automate this workflow by integrating AWS Device Farm into your continuous integration and continuous delivery (CI/CD) pipeline with the AWS Command Line Interface (AWS CLI) or AWS SDKs. The following are the key API operations:
CreateUpload: Upload your .apk and test package zip file.ScheduleRun: Start a test run with your test spec, app, and device pool.GetRun: Poll for run completion and retrieve the result status.ListArtifacts: Download test artifacts such as screenshots, videos, and logs.For GitHub Actions, use the official GitHub Action, which handles uploading your application and test package, scheduling the run, polling for completion, and downloading artifacts. For AWS CodePipeline, see AWS Device Farm test action reference. For other CI/CD tools or services, use the AWS CLI or AWS SDKs with the AWS Device Farm API.
AWS Device Farm pricing offers two models for automated testing:
The install phase (downloading Java and Maestro) adds approximately 1–2 minutes to each run. To optimize costs, run critical smoke tests on every commit and full regression suites on release branches only. For current pricing details, see the AWS Device Farm pricing page.
The following list describes common issues and their solutions.
appLaunchTimeout parameter in your flow YAML file.appops commands in the pre_test phase grant RUN_IN_BACKGROUND and START_ACTIVITIES_FROM_BACKGROUND permissions.export PATH commands in the install phase are correct. Environment variables that are set in one phase persist to subsequent phases.--test-output-dir points to $DEVICEFARM_LOG_DIR or a subdirectory. AWS Device Farm collects only files in paths that are listed under the artifacts section.To avoid incurring future charges, delete the following resources that you created during this walkthrough:
By integrating Maestro with the AWS Device Farm custom test environment, ManoMano transformed their mobile testing strategy. They moved from manual validation on a handful of devices to automated end-to-end testing across real physical hardware on every release. This approach delivers:
The key enabler is the AWS Device Farm custom test environment. With it, you can run any framework that operates over ADB, without being limited to officially supported test frameworks. This means you can combine the YAML-based test authoring in Maestro with a managed fleet of real devices and extend the pattern to other ADB-compatible tools as your testing needs evolve.
In this post, you learned how to configure the custom test environment, package your Maestro flows, handle manufacturer-specific restrictions, and automate the workflow in your CI/CD pipeline. To get started, create an AWS Device Farm project and try running your existing Maestro flows by following the steps in this post.
Post Syndicated from jzb original https://lwn.net/Articles/1105899/
Greg Kroah-Hartman has released the 7.3.2
and 6.18.61 stable kernels. Each contains quite
a few changes throughout the tree; users are advised to upgrade.
Post Syndicated from The Hook Up original https://www.youtube.com/watch?v=0BtHgs9dAUA
Post Syndicated from BeardedTinker original https://www.youtube.com/shorts/B1sRTLVOHt0
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=vnCIx4irKB4
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/11/pinpointing-location-of-videos-from-background-airplane-sounds.html
This is fascinating:
The video describes a technique that can reveal where an otherwise unidentifiable recording was made by analyzing its audio for the faint sounds of passing aircraft. The technique is both fascinating and frightening.
It works by looking at Doppler curves, which plot the way a plane’s sound changes as it passes overhead because of the Doppler effect. This is the same familiar Doppler effect that causes the frequency of a siren to rise as it approaches and then fall as it passes by and moves away. More generally, it’s the phenomenon whereby the frequency of a wave perceived by an observer changes when the observer and the source of the wave are moving in relation to one another.
[…]
It’s sound that’s relevant here, though, and specifically the sound of aeroplanes. Early in his video, Colsto brings up a map of the flights that were in the air at the time the video he’s tracing was recorded. Much of this information is publicly available. Aircraft equipped with Automatic Dependent Surveillance–Broadcast (ADS-B) transmit data about their position, velocity, and altitude, which flight-tracking services collect and make available to the public. While not every plane is tracked, the system provides an enormous amount of information about aircraft movements.
Post Syndicated from jzb original https://lwn.net/Articles/1105881/
Security updates have been issued by AlmaLinux (cockpit-files, container-tools:rhel8, delve, gcc-toolset-12-binutils, gimp:2.8, glibc, go-toolset:rhel8, kernel, libfastjson, mariadb:10.3, mod_auth_openidc:2.3, mysql:8.0, php:8.0, pki-core:10.6 and pki-deps:10.6, squid:4, tang, tesseract, thunderbird, and virt:rhel and virt-devel:rhel), Debian (chromium, ntfs-3g, puppet-agent, and trapperkeeper-authorization-clojure), Fedora (freerdp, goose, gpsd, hatch, perl-HTTP-Headers-ActionPack, perl-MIME-tools, perl-Plack, perl-Starman, proftpd, python-mistune, ruby-build, rust-crypto-bigint, rust-ctutils, rust-elliptic-curve, rust-num-bigint, rust-num-bigint0.4, rust-num-modular, rust-num-modular0.6, rust-num-prime, rust-zmij, rust-zstd, rust-zstd-safe, rust-zstd-safe7, rust-zstd-sys, rust-zstd0.13, scribus, sofia-sip, tailscale, tor, and wordpress), Oracle (cockpit-files, delve, firefox, gimp:2.8, kernel, and osbuild-composer), Red Hat (delve, git-lfs, go-toolset:rhel8, grafana, ignition, opentelemetry-collector, osbuild-composer, python-pillow, and yggdrasil), Slackware (openssh), SUSE (bind, brotli, cpupower, expat, fuse-overlayfs, go1.26, google-guest-agent, helm, ibus-typing-booster, kernel, kyverno, libmodplug-devel, librsvg, libX11, nvidia-open-driver-G06-signed, owntone, parted, perl-Cpanel-JSON-XS, perl-Text-CSV_XS, php8, python-Brotli, regclient, roundcubemail, rsyslog, and tomcat), and Ubuntu (ca-certificates, frr, haproxy, linux-nvidia-7.0, linux-nvidia-bos, linux-nvidia-tegra, and nginx).
Post Syndicated from Christopher Patton original https://blog.cloudflare.com/vole-mole/
The highest priorities for the transition to post-quantum cryptography are the basic building blocks of authenticated key-agreement protocols such as TLS. Without these building blocks in place, secure communication on the Internet will not be possible once cryptographically relevant quantum computers come online. However, today we rely on quantum-vulnerable cryptography for much more than TLS.
Privacy Pass is a protocol used by site operators like Cloudflare to help protect applications from abuse. One way we do this is by rate limiting individual clients so that no one client consumes too many of the site's resources. Normally this involves some combination of friction or loss of privacy for users: CAPTCHAs or other challenges to moderate traffic, along with accounts and fingerprinting to identify traffic.Privacy Pass was designed to avoid this tradeoff between friction and privacy. The basic idea is that a client gets issued a number of tokens, which they can redeem in exchange for access to the site. Crucially, each token is unlinkable to the client it was issued to, ensuring the client can use the site as they always had without sacrificing privacy.
With 10 years of deployment experience under our belts — using Privacy Pass for applications such as privacy proxies (like iCloud Private Relay) and relays (like Privacy Gateway) — we, along with others, are collaborating to bring the next generation of this technology to the web. One of our goals is to develop more sophisticated tools for managing agentic traffic that would otherwise consume too many resources and degrade performance for human visitors. Another goal is to foster a more open ecosystem by making it easier for more types of clients to participate. Achieving these goals requires developing new capabilities beyond what Privacy Pass offers today.
Given the trajectory, in this post we look at the prospects for post-quantum. In fact, we're in better shape than one might think. Privacy Pass still relies on classical cryptography, like RSA and elliptic curves. This means that a quantum attacker will be able to forge tokens at will and use them to bypass whatever security mechanism the site operator wants to implement (such as rate limiting). On the other hand, Privacy Pass is unconditionally private, meaning no attacker, quantum or not, can link the redemption of a token to its issuance. What's more, the new capabilities we're developing for this new generation of private authentication technology can and will be instantiated in a way that upholds the same guarantee: your interaction remains private even after Q-day.
This gives us a little breathing room, but we will need an alternative soon. This is an active area of research that has made significant strides in recent years. Still, just as is the case with other aspects of the transition, the primary challenge is the sheer size of post-quantum alternatives: ML-DSA-44 signatures are a whopping 2,420 bytes, while ECDSA-P256 signatures are just 64 bytes. And there's not much hope for drop-in replacements any time soon. Just as for TLS, we'll have to settle for primitives with higher cost and re-engineer our systems to bear this cost.
But what will those primitives be? In this post, we'll explore one potential future for post-quantum privacy on the web, made possible by a recent breakthrough in the design of blind signatures.
Let's start with an overview of this new technology, which is presently called MOLE ("Moderation Of unLinkable Endorsements"). We'll have much more to say about MOLE later on, but for now we'll highlight the details that are most relevant to cryptography.
One of the core components of Privacy Pass is a blind signature scheme, which allows a client to obtain a signature under an issuer's secret key without revealing to the issuer the message that it signed. The client can then reveal the message and blind signature later on without linking the signature to its issuance.
One type of Privacy Pass token consists of the message and blindly issued signature. To verify the token, the verifier needs the issuer's public key, and so necessarily learns the identity of the issuer. Thus while these tokens protect the identity of the client, they don't protect the identity of the issuer.
Of course, this is exactly what we want for some use cases. The identity of the issuer tells us something about what type of client is connecting to our edge, a signal we use to make decisions in some of our products and for some of our customers. For instance, a client might use a token issued by one of our customers to prove it is authorized to use the customer's VPN product.
However, for many use cases, this is more information than we actually need to make a decision to grant a client access to a resource. Normally we only care that the token was issued by some entity we trust. In fact, MOLE takes this a step further: the token should hide the identity of the issuer altogether so that we can't treat tokens differently based on who issued them. This guarantees equal treatment regardless of the type of client, making it easier for more clients to participate.
This issuer-hiding property is achieved through a new object called an endorsement. An endorsement is issued by an anchor and redeemed by a moderator. Before redemption, the client and moderator agree on an anchor set, the public keys of the anchors trusted by the moderator. During redemption, the client proves it was issued an endorsement by one of the anchors in the anchor set without revealing which one. Upon acceptance, the moderator issues the client the MOLE credential it will use to moderate the client's interaction with the site.
An endorsement can take many forms, but its key property is that it can be redeemed while hiding the identity of the anchor that issued it. There will also be many types of credentials, but because they're intended to be used by a particular moderator, they needn't be anchor-hiding or even publicly verifiable. This means that everything from blind signatures to anonymous credit tokens or anonymous rate-limited credentials can be used to instantiate MOLE credentials.
Now that we have a sense of what we're building, let's look at our options for post quantum.
When designing cryptographic protocols, adaptability and efficiency are often in tension. Sometimes we know exactly what we want to build and can tailor a construction for that purpose; but the more we tailor the protocol for that use case, the harder it becomes to adapt that construction to a different use case.
Adaptability is essential for a system like MOLE. We're not just building one kind of credential system, but many. And the types of credentials we need are likely to change over time, especially on the web where we must constantly adapt to new traffic patterns and attacker behavior. To keep up, we need a set of building blocks that can be composed together into different protocols to meet different requirements.
Most of the post-quantum cryptographic schemes in wide use today come from larger families of constructions, but have been tuned for their particular application. ML-DSA is a good example here: the cryptographic framework from which this scheme was derived can be used to build a variety of things, but to make ML-DSA as compact as possible, its parameters have been carefully tailored to build an efficient and secure digital signature scheme. However, the same parameters would not necessarily be secure for other use cases.
We have come to view this as the central challenge for post-quantum anonymous credentials: to decouple parameter selection from protocol design. Classical credential systems take this for granted: for the most part, protocol designers don't need to think about the parameters of the elliptic curve they're using, allowing even non-experts in the design of elliptic curve cryptography to build useful things with it. Unfortunately, designing efficient post-quantum credentials still requires an enormous amount of expertise.
This situation seems to have changed, however. Earlier this year, we saw a breakthrough that represents a potential sea change for anonymous credentials.
The roots of this breakthrough go back several years. We'll pick up the story three years ago, with the VOLE-in-the-Head (VOLEitH) zero-knowledge proof system (Baum et al., Crypto 2023). A zero-knowledge proof system allows one to prove knowledge of a hidden witness, satisfying some public statement while keeping the witness private. For example, a zero-knowledge proof can be used to prove knowledge of an AES key K for which Y=AES(K,X), where X,Y are public. This proof can be transformed into a digital signature whose security reduces to the security of AES, with X,Y as the public key and K as the secret key. This is exactly the FAEST digital signature, a candidate in NIST's ongoing signature competition.
Compared to many contemporary proof systems, VOLEitH is relatively simple to understand and implement securely. VOLE stands for "Vector Oblivious Linear Evaluation" and is an interactive technique that gives two parties correlated random values. These correlations act like authentication tags, allowing the verifier to check that a computation on the hidden witness was performed correctly. In VOLEitH, the prover prepares locally what the two parties would normally generate together — hence “in the head” — then commits to those values and uses the Fiat-Shamir transformation (a widely used tool in cryptography) to select the parts the verifier checks. This step turns the interactive VOLE process into a non-interactive zero-knowledge proof.
Apart from its simplicity, VOLEitH is a fairly unremarkable proof system. It's not succinct in the way many other proof systems are: its proofs are asymptotically linear in the size of the witness and the arithmetic complexity of the statement being proved. However, VOLEitH is concretely very efficient for a particular type of statement, namely one that can be expressed as a set of equations over small binary fields.
One example is the relation Y=AES(K,X) we just discussed. We don't normally think of AES as a set of equations, but many of its computations are designed around arithmetic in GF(28), a field whose elements are single bytes. FAEST proofs for this statement are only about 4KB (NIST Round 3, 128s).
Another example is the KuMQuat signature scheme, in which the signer proves an instance of the Multivariate Quadratic (MQ) problem. Here we're given a system of random, quadratic equations of multiple variables over a small field, like GF(28). Mathematically, this MQ map P looks something like P(s) = (sTA1s + b1s,…,sTAms + bms) where s and each bi are length n vectors and each Ai is an n-by-n matrix. Given P,P(s) for random s, the MQ problem is to find s. We call it quadratic because we multiply the elements of s by itself.
The MQ problem is believed to be hard to solve even for a quantum computer. But because P is made up of quadratic equations, proving knowledge of a solution with VOLEitH is fairly cheap, yielding KuMQuat signatures as small as 2.6KB.
When compared to other post-quantum signatures like ML-DSA or FN-DSA, these numbers don't look especially impressive. But how VOLEitH compares to other schemes in a particular category of constructions is beside the point. For MOLE, we'll need to strike a balance between performance and the ability to build many types of credential systems. To that end, we need one more ingredient.
Another way to build signatures from MQ maps involves embedding some additional mathematical structure into the map. In the Unbalanced Oil and Vinegar (UOV) signature scheme, the public key is an MQ map P, and a signature is a vector s satisfying P(s) = t, where t is obtained by hashing and salting the message to be signed.
The secret key for this signature scheme is a trapdoor for P with which the signer can derive solutions to the MQ equations. The trapdoor reveals to the signer a hidden partitioning of the variables of each quadratic equation into “oil” and “vinegar” variables. Oil variables are never multiplied by one another, so fixing the vinegar values turns the equations into a linear system that the signer can solve for the oil values. In the public key, oil and vinegar variables are mixed together in a way that hides this structure in the map.
UOV is also a candidate in NIST's ongoing signature standardization effort. It has one of the smallest signatures among the candidates, at just 135 bytes. The trade-off is that it has the largest public keys, at 46.6KB. MAYO is another multivariate candidate with much smaller public keys, at the cost of slightly larger signatures.
The key thing to take away here is that the arithmetic complexity of evaluating a UOV (or MAYO) signature is comparable to evaluating an MQ instance. Both are public quadratic maps over small binary fields, making them a good fit for VOLEitH. This brings us to the breakthrough.
Earlier this year, a blind signature called PoMFRIT was published (Baum et al., USENIX Security 2026) that achieved what at the time was a record for candidate post-quantum constructions: 6.7KB for the blind signature itself and just a few hundred bytes for issuance. PoMFRIT is based on VOLE-in-the-Head and the MAYO multivariate signature. We can easily drive the size of the signature down to 4.3KB by swapping MAYO out for UOV. (This figure uses NIST round 3 parameters for UOV (uov-Ip) and FAEST-EM-128s.) The trade-off is larger public keys, but this pays off in applications where a public key can be cached and used sufficiently often.
This is competitive with state-of-the-art lattice-based constructions. But the really good news is that building blocks of PoMFRIT can easily be reconfigured into all of the credential systems we've considered for MOLE, including endorsements. More on this in a bit: for now, let's look at how PoMFRIT works in more detail.
A well-known paradigm for designing blind signatures is the following. First, the client places the message in the cryptographic equivalent of a sealed envelope, called a commitment. For our purposes, a commitment is simply the hash of the message together with some randomness generated by the client. To complete issuance, the signer simply signs the commitment directly.
To construct the blind signature, the client produces a zero-knowledge proof of knowledge of the signature and the randomness it used to compute the commitment, called the opening. A verifier would use the signer's public key to verify this proof.
Let's define a bit of notation to make this clearer:
r and sends a commitment c=H(m,r) to its message m to the issuer.s=Sign(sk,c) and sends it to the client. It doesn’t learn the message as it’s hidden behind the hash.π of knowledge of s,r for which Verify(pk,H(m,r))=1,The proof π is the blind signature. It can be verified by any party in possession of the issuer's public key pk and the message m.
Unlinkability comes from the client presenting entirely different objects during the two phases: a commitment is shown to the issuer during issuance, and a zero-knowledge proof is shown to a verifier during presentation. Even if the issuer and verifier collude or are the same entity, they cannot link the sessions.
The size of the proof π is dominated by evaluation of the hash, so we need to choose a hash function that is friendly for our proof system. For most proof systems, such proof-friendly hashes are not well studied, but for VOLEitH it turns out that the Keccak permutation used in SHAKE and TurboSHAKE is a good choice. Keccak’s bitwise operations translate natively into VOLEitH constraints: XOR becomes addition, AND becomes multiplication, and rotations simply rearrange values. (Many popular SNARKs, by contrast, are designed for large prime fields, making byte- and bit-oriented operations less natural to express.)
Nevertheless, Keccak evaluations end up being the largest component of the VOLEitH proof, so we need to make sure we're using only the minimum necessary number of permutations. PoMFRIT requires two: one for the commitment and another for the signature. Concretely, the statement we prove is roughly P(s)=H(H(m,r),rs) where s is the signature, rs is a salt chosen by the issuer, P is the issuer's UOV public key, and H denotes the Keccak permutation with the output truncated to the appropriate length, which also prevents anyone from inverting.
Recall that for MOLE endorsements, we need something like a blind signature, but one that doesn't reveal the anchor that issued it. That is, we now have a sequence of anchor keys P1,…,PN, and the statement we now want to prove is Pi(s)=H(H(m,r),rs) for some anchor key Pi whose index i is now part of the hidden witness.
With some care, we can write this as a set of constraints with roughly the same cost: two hashes and one MQ evaluation. We need to prove a bit more about the witness. What exactly? We won't spoil it for you: ZK circuit design is part of the craft of cryptographic engineering that makes it so fun. We'll just say the kind of thinking needed here is transferable to just about any modern proof system you might encounter.
Even more advanced credential systems can be constructed in this framework, including the aforementioned anonymous credit tokens and anonymous rate-limited credentials. In both of these cases, the primary cost is an additional hash or two. Each of these also requires proving that part of the witness (e.g., the credit count) is in some expected range, but this is low cost in VOLEitH.
Indeed, for every construction we have considered so far for MOLE, the primary cost is the size of the Keccak evaluation and how many times we need to evaluate it. This means that finding ways to reduce the amount of hashing yields improvements across the board.
Before we go any further, we need to acknowledge that cryptanalysis of multivariate cryptography is still relatively immature. We have seen advances against several parameter regimes in just the last couple of years, Both UOV and MAYO have weathered these attacks well, and an outright break of UOV and even MAYO seems more unlikely with every passing year. But we should at least expect the parameters to change in a way that adds a bit of cost to our constructions.
On the other hand, it's not uncommon for credential systems used in practice to adopt a less-than-conservative security posture for the sake of performance in so far as it affects forgery resistance. This typically means relying on stronger-than-usual computational assumptions. That is, it's possible that a (pre-quantum) attack might come along that breaks anonymous credit tokens, but not ECDSA, despite the fact that they both use the same elliptic curve.
PoMFRIT achieved its size record by doing precisely the same thing. Recall that the blind signature requires proving two hash evaluations, one by the client and the other by the issuer. PoMFRIT observes that VOLEitH proof generation can be split into two stages. In the first stage, the client commits to a random mask. It then hashes the message normally (outside of the ZK circuit), combines the result with the mask, and sends the masked target to the issuer. The issuer uses the UOV trapdoor to find a preimage of this target. In the second stage, the client completes the proof that the preimage and previously committed mask are consistent. The hash remains part of the protocol, but the issuer — acting as the VOLEitH verifier — can compute it directly rather than requiring the zero-knowledge proof to reproduce it.
This strategy substantially reduces proof size, but it also changes our security posture. The plain UOV assumption is that no (quantum) attacker can find a pre-image for a random target without knowledge of the trapdoor. The corresponding one-more-UOV assumption (analogous to the one-more-MAYO assumption in the PoMFRIT paper) neatly captures the additional information available to the attacker as a result of this kind of optimization. The assumption, then, is that this additional information doesn't lead to an attack.
This assumption may turn out to be overly optimistic. Recently, researchers at the University of California, San Diego, and INRIA managed to forge a 1024-bit RSA signature using a Privacy Pass issuer as a signing oracle. Fortunately, Privacy Pass uses 2048-bit RSA, which, in concert with other defense mechanisms, provides a pretty good security margin. Likewise, for UOV we might consider using NIST Level 3 parameters instead of Level 1.
In any case, a bit more study will be required before we rely too heavily on these kinds of optimizations. It's worth emphasizing that a break here would only impact an attacker's ability to forge tokens, not the attacker's ability to violate a client's privacy.
Standard SHAKE uses a 1600-bit Keccak state with 24 applications of an underlying round function. However, since the SHA-3 standard was published, many have come to believe that 24 rounds is just too much crypto. TurboSHAKE works the same way, except the permutation uses 12 rounds instead of 24. This substantially reduces the size of VOLEitH proofs. In fact, we're quite comfortable with this security margin, and not just for this application.
Another change to Keccak that reduces the proof size is to reduce the size of the state. 256 bits of the state are reserved for the capacity to get 128 bits security. That leaves 1344 bits that can be hashed in one go, which is more than we need. Reducing the state by half to 800 bits leaves us with a rate of 544 bits, which is plenty. On top of that, it even increases the security at the same number of rounds, as an attacker has less to play with. The smaller state means we’re using half the multiplications in our circuit, which reduces the size of the proof.
In an ideal world, we could avoid proving conventional hashes altogether by replacing each hash with something that composes more natively with the algebraic structure of our primitives. Indeed, those familiar with Pedersen commitments and their use in elliptic curve cryptography may wonder if commitments can be constructed from multivariate cryptography.
This might look something like this: Fix public, random MQ maps F and G and commit to a message m using c=(m+F(r),G(r)). The advantage of this approach is that the degree of the constraints is the same as the degree of the constraints for the UOV signature. Not only does this make the proof smaller, it makes it far simpler, since we avoid evaluating symmetric crypto in ZK altogether.
We experimented with this approach for our application, and it yielded some impressive results. However, it's not at all clear yet if the parameter regime in which multivariate commitments yield an improvement is also secure. Notably, the risk here is not just to unforgeability, but also to client privacy. A lot more study is needed.
Another direction is to build an MQ-friendly pseudorandom generator (PRG).
For typical VOLEitH parameters, adding an extra witness bit adds ten bits to the proof. There is a neat trick to make this a lot cheaper: only one bit of proof per bit of witness! Instead of using VOLEitH directly, we commit to a (relatively) short key. That key we stretch into a larger bitstream using a PRG with low-degree so that it can be computed cheaply in the circuit. Now, to add a witness bit w, we get one extra bit k from the PRG, and store the bit w XOR k in the proof.
There is a performance trade-off: we need to compute the PRG and the witnesses start at degree 2 instead of 1. That especially increases prover time. Also the benefits on proof size only start to pay off when you need a decent number of witness bits.
And of course you need a PRG! You can create a PRG using a random MQ instance, but that’s very slow and seems overly conservative. At the other end is the Goldreich PRG, which can be seen as an as-sparse-as-possible MQ PRG. We’d want something in between, but such PRGs haven’t received much study.
We already have post-quantum privacy today, so we have some time before we need to have a solution in place, but now is the time to develop alternatives.
Multivariate cryptography looks to be a promising basis for easily building a variety of anonymous tokens and credentials. We're currently developing two schemes in this framework: VOLE-IHAT, a candidate for MOLE endorsements, and VOLE-ACT, a candidate for MOLE credentials. Our current cost estimates for these are shown in the table below. The numbers here are subject to change as we analyze and develop these constructions. We use UOV (uov-Ip) in each case, which means the public keys are all 46.6KB. VOLEitH uses the same parameters as FAEST-EM-128s:
|
issuance |
presentation |
|
|
PoMFRIT (with UOV) |
<1KB |
4.3KB (redemption) |
|
VOLE-IHAT |
5.6KB |
6.5KB (redemption) |
|
VOLE-ACT |
5.4KB |
12.0KB (spend) |
These numbers are significantly larger than their classical counterparts. This comes as no great surprise, as "PQ is big" is really the main hallmark of the transition across the board. However, replacing RSA blind signatures with PoMFRIT has comparable overhead to replacing ECDSA with ML-DSA. The runtimes of these protocols are also excellent: each operation takes just a few milliseconds with our implementation. (Runtime can be improved by quite a bit, though at the cost of higher communication.)
If these numbers hold, then we've already reached an important milestone: the transition to PQ anonymous credentials for the web can now shift from cryptography design to protocol engineering. In other words, we think we can make these numbers work. For example, whereas classical blind signatures might be cheap enough to redeem on every request, we'll have to figure out how to amortize a single redemption over multiple requests.
We have some work to do before we get there. First, we need to make sure our protocols are sound, in particular by producing security proofs for them that show they are secure as long as UOV is secure. Second, we need to wait a bit for cryptanalysis of UOV to catch up. We encourage cryptographers to spend time with multivariate cryptography. Once the parameters stabilize, we believe these schemes will find a place in a ton of useful applications. We've only just scratched the surface so far.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=6j-OZdcBmxk
Post Syndicated from Емилия Милчева original https://www.toest.bg/yotova-li-specheli-ili-gyurov-zagubi/
На избори обикновено се състезават обещания за по-добро бъдеще, но на балотажа за президент в България победи обещанието да не стане по-лошо.
Лидерът на ГЕРБ Бойко Борисов години наред печелеше избори с предупреждения за хаоса, който ще настъпи без него. Румен Радев усъвършенства тази политическа технология, като прибави и страха от война към страха от нестабилност. На президентските избори технологията отново проработи, а премиерът (и президент почти два мандата) си приписа заслугите за победата на Илияна Йотова. Същевременно опозицията им не успя да убеди достатъчно избиратели, че промяната не е поредната заплаха.
Да си прав за агресията на Русия срещу Украйна, за европейския избор на България и за опасностите от политическото заиграване с Кремъл не означава непременно да печелиш избори.
Властта успя да превърне войната на Русия срещу Украйна в риск, който уж произтича от противниците на управлението на страната. В държава членка на НАТО, на чиято територия са разследвани (руски) саботажи и която е мишена на дезинформационни и хибридни операции, управляващите представят не Русия, а политическите си противници като заплаха, по-голяма от режима на Путин. Така агресорът остана на заден план, а опасността беше приписана на онези, които му се противопоставят.
Балотажът, както е добре известно, не се печели само със собствените избиратели. Между двата тура кандидатите трябваше да търсят подкрепа извън твърдите ядра и симпатизантите си.
Резервоарът на гласове за Йотова беше гарантиран още на първия тур от кандидатпрезидентските двойки на „Възраждане“, „Величие“ и дори МЕЧ (независимо от призива на лидера Радостин Василев да се гласува за Гюров). Третите на 25 октомври – „Възраждане“ с лидера си Костадин Костадинов и евродепутата Петър Волгин, спечелиха близо 191 000 гласа. Част от тях преминаха на втория тур към Йотова поради липса на българска Алис Вайдел. Но и наративът на Йотова и подкрепящите я е също като на лидерката на „Алтернатива за Германия“.
Противопоставянето „мир или война“ в кампанията за президент в България не е изолиран феномен. В Европа, не без помощта на Кремъл, се оформя нов политически речник, в който капитулацията се нарича мир, съпротивата – ескалация, а солидарността с нападнатия – подстрекателство към война.
В интервю за The Economist Алис Вайдел говори с добре познати и на българското общество тези, които се налагат от управляващата „Прогресивна България“, от говорители като Явор Дачков и Мартин Карбовски, от някои социолози и анализатори, от Йотова–Вълчев, Костадинов–Волгин, „Величие“, МЕЧ и Радостин Василев. Един твърде шумен и многолик, но единогласен хор.
Украйна вече е загубила войната. Подкрепата за Украйна е опасност от разширяване на войната и Германия може да стане мишена.
На въпрос за предполагаем руски опит за атака с дронове на летището в Лайпциг Вайдел заявява, че не е видяла доказателства за руска отговорност. Също като българските управляващи, които упорито отказват да посочат Русия като стояща зад атаките с дронове по търговски кораби в Черно море.
Когато питат Вайдел за отговорността на Путин, тя измества разговора към президента на Украйна Зеленски. Оказва се, че нападнатата страна трябва да доказва, че иска мир. Така лидерката на германските крайнодесни се измъква от неудобни въпроси, като обръща посоката им. По същия начин действа с въпроса за дроновете – насочва разговора към предполагаемата украинска роля във взривовете на газопроводите „Северен поток“.
В бойното изкуство джудо силата на противника се използва срещу самия него. На този принцип се основава и т.нар. вербално джудо – комуникационна техника, популяризирана от американеца Джордж Томпсън, бивш преподавател и полицай. Нейната цел е да овладява конфликти чрез пренасочване на разговора, без агресия и насилие.
В политиката обаче подобен подход може да се използва и за манипулация. Тази тактика напомня на т.нар. DARVO (от английските Deny, Attack, Reverse Victim and Offender), при която обвиненият отрича, атакува обвиняващия и разменя ролите на жертва и извършител. Вместо да отговориш на неудобния въпрос, обръщаш го срещу онзи, който го задава. Атакуваш, вместо да се защитаваш. И докато противникът се опитва да опровергае обвиненията, никой вече не помни въпроса.
Съвпадения с пропагандния речник на Кремъл се откриват в наративите на различни европейски политици. На 21 октомври The Insider разкри документи и вътрешна кореспонденция за руската операция за влияние „Допелгенгер“. От тях става ясно, че още през април 2022 г. Сергей Кириенко – първи заместник-ръководител на президентската администрация в Русия, който отговаря за вътрешнополитическите процеси, и един от най-влиятелните хора в Кремъл, поставя пред пропагандистите три задачи: да създадат „ядрена психоза“, да водят „война в името на мира“ и да преувеличават всичко. През март 2024 г. при опасения от нарастваща подкрепа за Зеленски във Франция са предложени посланията „чужда война“ и „Европа има нужда от мир“.
Месец преди балотажа премиерът Румен Радев извади ядрената карта. На форум на Euronews в Брюксел на 30 септември той предупреди, че Русия може да прибегне до ядрено оръжие, ако бъде отслабена или притисната. Попита защо никой не оценява риска от опитите за конвенционална победа над най-голямата ядрена сила, и настоя да бъдат чути тревогите и на двете страни. Така заплахата, отправяна от Москва, се превърна в аргумент за сдържаност на Запада.
След първия тур Радев вече не говореше за хипотетична ядрена ескалация, а за избор между мир и война. На 26 октомври той обяви, че политическите му противници не биха се поколебали да въвлекат България във войната. За месец опасността смени адреса си: от руския ядрен арсенал към българската опозиция.
В телевизионния дебат Йотова продължи тази линия. Според нея наливането на повече средства и по-модерни оръжия в Украйна води единствено до нови разрушения и човешки жертви. Тя напомни, че загиват хора от двете страни – славяни и православни християни. Общата религия и произход се оказаха по-важни за аргумента ѝ от разликата между агресор и нападнат. А подписаното от Гюров споразумение с Украйна беше използвано, за да бъде внушена опасността от изпращане на български войници, въпреки че това може да реши единствено българският парламент.
Така войната, започната от Путин, беше превърната в предизборно обвинение срещу противниците на Радев. Докато те трябваше да доказват, че няма да изпращат българите на фронта, управляващите си присвоиха правото да говорят от името на мира.
Технологията на внушенията беше използвана и срещу Андрей Гюров. Анализ на компанията Identrics проследява как твърдение за негов спонсор, свързан с производството на дронове в Украйна, преминава през сайтове, социални мрежи и политически говорители, докато се превърне в обвинение, че кандидатът е финансово обвързан с военната индустрия. Според анализа Мартин Карбовски също разпространява твърдението във Facebook, повтаря го на среща с граждани във Велико Търново и Илияна Йотова.
Според публикация в сайта „Гласове“ на Явор Дачков, чиято съпруга Йотова назначи за съветник в Президентството, Данчев е най-големият дарител на „Продължаваме промяната“ през 2025 г., а за президентската кампания на Андрей Гюров е предоставил общо 150 000 евро.
Калоян Данчев притежава българската „Дженерал Чери интернешънъл“, в чийто съвет на директорите е Кирил Петков. През юни се появяват публикации за намерения двамата да развиват производство на дронове по украински лиценз.
На 29 октомври „Гласове“ публикува данни от естонски регистри, според които Петков е участвал в срещи с отбранителни институции като представител на делегация на украинския производител на бойни дронове General Cherry. Тези обстоятелства не доказват, че дарението му обвързва Гюров с военния бизнес или с каквато и да било политика на въвличане на България във войната.
Президентът е върховен главнокомандващ на въоръжените сили, но това не означава, че може еднолично да изпраща български войници на война. Той назначава и освобождава висшия команден състав по предложение на Министерския съвет, а решението за изпращане на български войски извън страната принадлежи на Народното събрание.
Първият тур на президентските избори показа, че Йотова може да бъде победена: разликата с Гюров беше под 3% и почти 43 000 гласа. Вторият тур разби надеждите.
За Илияна Йотова гласуваха 57,6% от отишлите до урните, а за Андрей Гюров, подкрепен от „Продължаваме промяната“, „Демократична България“ и други формации от демократичната общност – 39,5%. В гласове разликата надхвърли 300 000.
Утешението е, че Гюров получи близо 750 000 гласа, една част от които са дошли от ГЕРБ. Все пак вотът е сериозен политически капитал за човек, станал широко разпознаваем благодарение на 78-те си дни като служебен премиер и обявил кандидатурата си само два месеца преди изборите. Така беше пропуснато ценно време не само за утвърждаването му като кандидат, но и за достигане до избиратели извън традиционните среди на ПП, ДБ и подкрепящите ги формации. (За сравнение, на парламентарните избори на 19 април коалицията ПП–ДБ получи 408 846 гласа, впоследствие се разпадна на двете си съставни части.)
Кампанията показваше Гюров как цепи дърва, лови риба и меси питка, но твърде малко от това какъв президент възнамерява да бъде. Вместо да разширява представата за политическите му възможности, тази кампания сякаш се опитваше да го направи симпатичен на хора, които бездруго бяха готови да гласуват за него.
Градската десница от години се сблъсква с един и същ проблем: знае срещу кого се бори, но трудно убеждава избирателите за какво се бори. Борбата с корупцията, съдебната реформа, европейската ориентация на България са важни каузи. Но те не са достатъчни, ако остават политически език, разбираем и убедителен предимно за хората, които така или иначе споделят тези убеждения.
Гюров трябваше да бъде кандидат не само на онези, които не искат Радев и Йотова, а и на хората, които нямат доверие нито на управляващите, нито на техните противници. За тях въпросът не е единствено кой е по-европейски настроен, кой е по-последователен в подкрепата за Украйна или кой има правилна позиция за съдебната власт. А защо и как един различен от управляващите президент би помогнал животът им, държавата им и бъдещето на децата им да станат по-сигурни.
Вместо да постави управляващите в положение да обясняват собствените си решения, по време на кампанията си Гюров твърде често трябваше да отговаря на техните обвинения. Така се състезаваше на терена, избран от противника. Докато единият кандидат обещаваше мир, другият трябваше да доказва, че не иска война.
Гюров не беше безмълвен пред властта. След ударите с дронове по кораби в Черно море той обвини Йотова, че е превърнала президентската институция в ехо на правителството. В телевизионния дебат с нея говори за бюджета, инфлацията, свободата на медиите и президентското вето. Но тези позиции не успяха да определят дневния ред на кампанията. Вместо да се превърне в разговор за отговорността на управляващите, предизборният спор отново и отново се връщаше към въпроса дали Гюров няма да въвлече България във война.
Разбира се, президентът не управлява икономиката, не разпределя бюджета, не се занимава с данъците. Но има право на вето, назначава служебно правителство при определените от Конституцията условия, участва във формирането на ключови институции и може да задава политически дневен ред. Кампанията даваше възможност да се покаже как държавният глава може да бъде коректив на властта. Румен Радев го правеше непрекъснато през двата си мандата, както и чрез служебните правителства.
Но има и още нещо: колко пъти демократичната общност може да обяснява изборните си поражения с пропагандата, зависимите медии, купения вот и страховете на избирателите, без да потърси причините и в себе си? Всички тези фактори имат значение. Не обясняват обаче защо политическите ѝ послания толкова трудно прекрачват границите на собствения ѝ електорат.
А какво следва за Андрей Гюров? Близо 750 000 гласа му дават политическа тежест, но не и автоматично политическо бъдеще. Ще остане ли лице на демократичната общност, ще потърси ли собствено място в партийния живот, или ще се оттегли отново от първата линия?
Разпадането на коалицията ПП–ДБ прави този избор още по-сложен. Гюров получи подкрепа, която надхвърля електората на двете формации, но тепърва трябва да покаже дали може да я превърне в трайно политическо доверие и за каква цел.
Ако прави собствена партия, ще откъсне живо месо от двете сили – типичното за общността самоизяждане, един изчерпан вече модел на политическо роене. Трудно е и да бъде издигнат за кандидат за кмет на София предвид намерението, макар и незаявено публично, на Васил Терзиев за втори мандат. В случай че се мисли в тази посока, от ПП и ДБ се очаква да направят оценка на работата на столичния кмет и да обяснят публично защо не биха го подкрепили за втори мандат.
В интервю за „Дневник“ съпредседателят на „Да, България“ Ивайло Мирчев посочва, че демократичната общност се разширява и Гюров, който е допринесъл за това, има място в нея. Чудесно, но как? Създаването на нови политически конструкции, които пренареждат едни и същи избиратели, не привлича нови.
През януари 2027 г. Илияна Йотова ще се закълне като седмия президент и първата жена на този пост, след като изкара 9 години като вицепрезидентка и една като действащ държавен глава. Предстои ѝ петгодишен мандат, след който Конституцията дава шанс да се пробва и за втори.
Илияна Йотова ще се сдобие с политическо дълголетие на висок пост, по-голямо от това на лидера на ГЕРБ Бойко Борисов като трикратен премиер. Тя е единственият политик от БСП, чиято кариера, започнала още през 90-те, неизменно е била във възходящо движение – между пресцентъра на „Позитано“ 20 и позицията ѝ на „Дондуков“ 2 тя премина през столичната организация на БСП, беше депутатка и евродепутатка. Избирателите на БСП съвсем оредяха, но структурите останаха и работиха енергично за кампанията ѝ.
Така партията се оказа в парадоксалното положение да остане извън парламента, но да има свой политик за президент – разбира се, с подкрепата на управляващата „Прогресивна България“.
Йотова си осигури още пет години политическо бъдеще, като превърна бъдещето на България в повод за страх. Ще успее ли да предложи нещо повече?
Post Syndicated from Йоанна Елми original https://www.toest.bg/glasovete-na-amerika-broy-20/
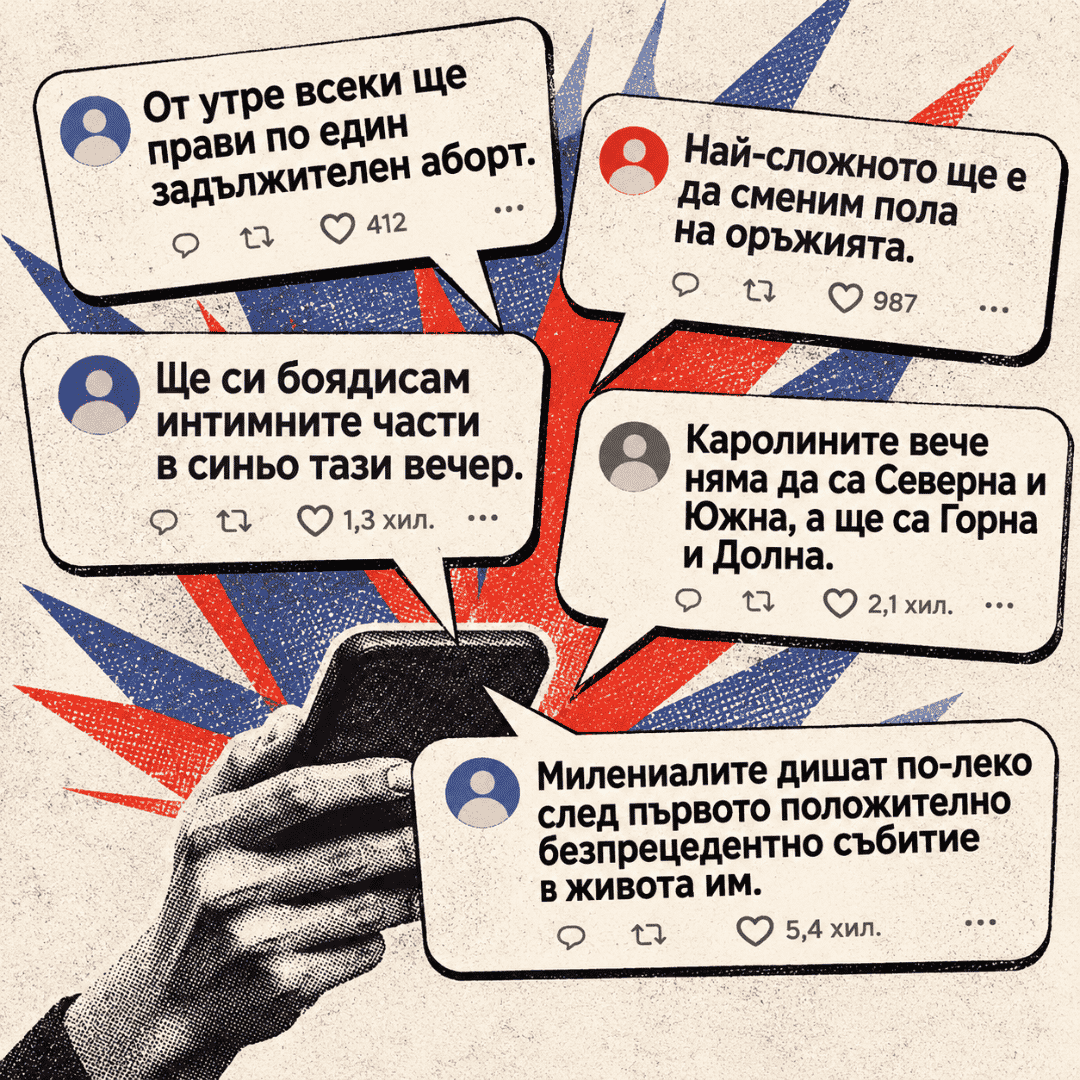
Това са само част от коментарите в социалните мрежи след историческата синя вълна, която заля САЩ на междинните избори във вторник, 3 ноември 2026 г. Както често се случва, никой не успя да предскаже голямата история – дори силно положителните прогнози в полза на демократите не се приближиха до реалността. Американските медии говорят не за вълна, а за цунами. Последвалото цунами от анализи, мнения и прогнози е не по-малко мощно.
Затова ето обобщение за междинните избори в САЩ накратко в десет точки.
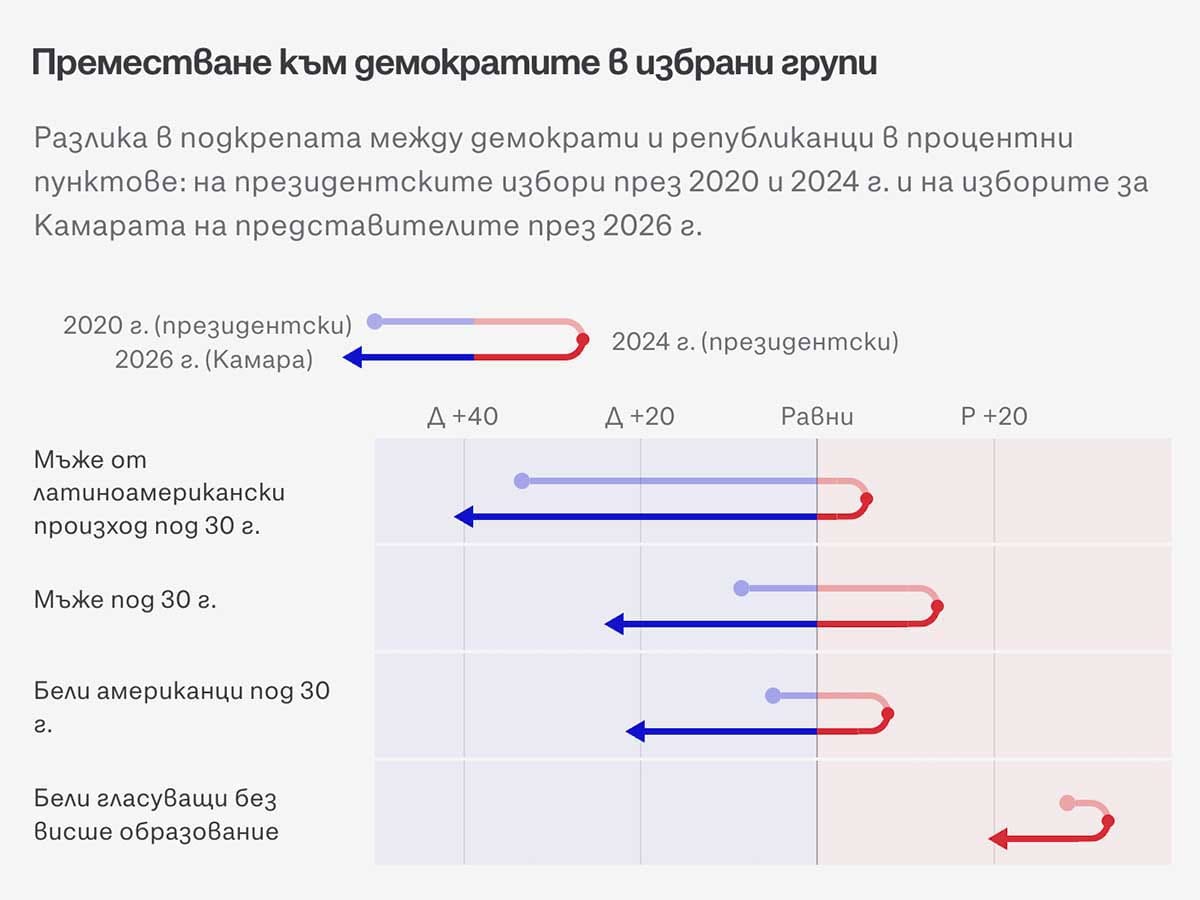
Независимо дали разглеждаме населението по пол, раса, възраст или образование, Америка прави рязък завой към Демократическата партия. При мъжете под 30 години преместването вляво е с 38 пункта, при белите американци под 30-годишна възраст е с 30 пункта, а най-голям обратен завой са направили мъжете от латиноамерикански произход под 30 години – 47 пункта по-голяма подкрепа за демократите. Дори белите гласуващи без висше образование, които традиционно подкрепят Тръмп, са се преместили 14 пункта вляво.
Демократите обръщат някогашни бастиони на републиканизма, като Канзас, който не е имал сини представители в Сената и долната камара от почти сто години насам. За последния половин век нито една партия не е вземала повече от две места, спечелени в предишни избори от опозицията с повече от 10 точки преднина. Демократите със сигурност печелят между пет и седем такива места – в Айова, Канзас, Охайо, Южна Каролина, Тексас, като Аляска и Мисури са почти преброени и сигурно също ще се обърнат в синьо.
Канзас избира демократ за последен път през 1932 г. – три години след началото на Голямата депресия, когато Демократическата партия е много различна. Тексас не е бил син от 1988 г. и бе толкова сигурно републикански, че Илон Мъск се премести там, за да избяга от демократите в Калифорния.
Южна Каролина не е променяла цвета си от 2002 г. насам, Айова и Северна Каролина последно гласуват за Обама през 2008 г. Охайо беше традиционно смятан за колебаещ се щат, но оставаше непоколебимо червен през последните шест години. Това обаче може би отново ще се промени. Мейн също е колебаещ се щат с необичайно висока подкрепа за независими кандидати – този път спечелиха демократите.
Така или иначе, без много за губене демократите инвестираха сериозни средства в кампании, насочени към места, които Тръмп бе спечелил с огромна преднина през 2024 г. На това се дължат изненадите в Канзас, Южна Каролина и Тексас. Те вероятно нямаше да бъдат толкова големи, ако войната на Тръмп в Иран не бе вдигнала цените на горивата, а хаотичните мита не бяха причината за допълнително поскъпване на живота и стоките. Блокадата на Ормузкия проток доведе не само до трусове в световната енергетика, но и смути доставките на торове, което директно се отрази на земеделците в тези щати.
Сред причините резултатите от тези избори да са толкова неочаквани е политическото втвърдяване, за което сме говорили и друг път – силното поляризиране на избирателите в две идеологически крайности, от които се излиза трудно. Президентът Тръмп стана емблемата на този феномен: независимо колко скандали, корупция и проблеми породи неговата фигура през годините, изглеждаше, че той има имунитет, защото въплъщаваше идеологическата визия и искания на своя електорат и привличаше и независими избиратели към себе си.
Речта на преизбрания за сенатор на Джорджия Джон Ософ, сочен като един от фаворитите за кандидат-президент след две години. Пълния превод може да прочетете тук.
Избирателите обаче посочиха високите цени, войната с Иран, липсата на достъп до добро здравеопазване и корупцията по високите етажи на властта като основни проблеми. И въпреки че вместо да признаят грешките си, през цялата кампания републиканците отново заложиха на културни войни, говорейки за трансджендъри, страшни мигранти и комунизъм, реалността просто се оказа по-силна.
Тактиката с всяване на страх се превръща в сатира, защото все повече хора виждат, че не отговаря на реалността. Не помогна и това, че президентът до последно беше съсредоточен да убеждава хората, че е най-успешният лидер на САЩ в историята. Както и че собствената му партия така и не успя да му противостои – отчасти защото втвърденият ѝ електорат не позволи, а когато вече бе възможно, политиците просто не реагираха навреме и с достатъчно натиск.
След края на Студената война и двете партии претърпяват промени, които отразяват разклащането на обществото: след разочарованието от ерата на Буш-младши и нахлуването в Ирак расте недоверието към институциите и медиите, което кулминира в победата на Обама – първия чернокож президент, през 2008 г.; това пък хвърля в истерия дясното и медийния му балон (добре известна е историята на Роджър Ейлс и Fox News, превърната и в популярен сериал).
По времето на Обама по-екстремните крила на републиканците бавно превземат партията, а Тръмп се появява като последен симптом на болното си време и срутва окончателно умерените фронтове вдясно. След 2000 г. неравенствата в САЩ се задълбочават, финансовата криза и войните в Близкия изток белязват обществото, животът става все по-скъп, средната класа живее все по-трудно, медийният пейзаж се фрагментира, а парите навлизат все по-безочливо в политиката.
Клипът, с който Джош Турек обявява кандидатурата си за Сената в Айова. В него бившият баскетболист, печелил злато за страната си, разказва за заболяването си – вродена спина бифида, причината за която е излагането на баща му на хербицида „Агент Ориндж“, използван от САЩ по време на войната във Виетнам.
Импулсът, който докарва Тръмп на власт, е популистки – той се обявява срещу институциите, системата, обещава да „изчисти блатото“ във Вашингтон. Без повече войни в Близкия изток, по-евтин живот, справедливост. Тези обещания резонират с очакванията на избирателите през 2016 г., въпреки че тогава губи популярния вот.
За завръщането му през 2024 г. пък помага тоталната немощ на демократите да изберат обединяващ кандидат, който да бъде ново лице на партията и да внесе качествени промени – вместо това на власт след пандемията бе Джо Байдън, чийто когнитивен упадък бе отричан системно от партията, преди да стане твърде очевиден. От обещанията на Тръмп обаче минаха десет години, властта никога не е била по-явно корумпирана, а всяко едно от въпросните обещания бе нарушено – не на последно място защото е невъзможно например да осъществиш масови депортации, когато икономиката на държавата ти зависи от мигрантски труд.
Нито Хилари Клинтън, нито Джоузеф Байдън можеха да бъдат лицето на промяната, от която има нужда страната – напротив, в очите на американците те са част от същата политическа класа, неуспяла да се справи с проблемите в зародиш. Част от привилегията на Тръмп бе именно да бъде възприеман като аутсайдер. Днес демократи като Абдул Ел-Сайeд от Мичиган също използват популистки език, само че с лява насоченост, като в една от предизборните си реклами споменава и факта, че е трябвало да се пребори със собствената си партия, за да бъде издигнат.
Предизборна реклама на Абдул Ел-Сайед, в която се появяват баба му и дядо му. „Откъде е Абдул Ел-Сайед“, започва рекламата, имитирайки апокалиптичната и плашеща естетика, характерна за републиканския ксенофобски наратив. „Оттук, ние го отгледахме, а той ни носи покупки всяка седмица и знае кое колко струва“, разказват те.
Макар и все още да нямаме данни за средната възраст на избраните за Камарата на представителите и Сената, със сигурност се отдалечаваме от геронтокрацията на последното десетилетие. През по-голямата част от кампанията на междинните избори прожекторите бяха върху нови лица, които често побеждаваха по-опитни членове на партията в предварителните избори, привличаха огромни публики и обещаха да променят приоритетите на демократите, щом стигнат до Вашингтон.
Сред най-разпознаваемите примери са: 37-годишният Джеймс Таларико, който спечели сенаторското място в Тексас; 47-годишният Джошуа Турек от Айова; Адам Хамилтън, на 62, който обърна Канзас; 46-годишната сенаторка д-р Ани Андрюс от Южна Каролина, която победи сестрата на починалия сенатор Линдзи Греъм. Ръководството на партията положи неимоверни усилия да открие хора, които резонират с избирателите във всяка една област. А после им даде път напред, вместо да ги саботира, както ставаше през последните години.
Предизборна реклама на д-р Ани Андрюс, в която участва и баща ѝ – републиканец, гласувал за някогашната ѝ опонентка Линдзи Греъм. Д-р Андрюс набляга върху разочарованието от двете страни на политическия спектър, а баща ѝ казва, че дъщеря му със сигурност не е „луда социалистка“.
В кампанията на демократите осезаемо липсваха някои от по-крайните проявления на социалната политика, които им костваха избиратели през последните десет години. Д-р Андрюс например се съсредоточи върху критика към здравния министър Робърт Кенеди-младши и обвини администрацията на Тръмп за епидемията от морбили в щата си.
В своята предизборна агитация Адам Хамилтън заложи на това, че Канзас е щат в центъра на страната и се намира далеч от крайностите и поляризацията във Вашингтон. В началото на годината Хамилтън е регистриран републиканец, променя партийната си принадлежност и води кампания, основна на вярата му – Хамилтън е пастор в най-голямото методистко паство в страната. Таларико от Тексас също залага на вярата си, връщайки християнството вляво.
Както в Камарата на представителите, така и в Сената мнозинството на демократите ще бъде многообразно – от по-левите представители, като Ел-Сайед и Трой Джаксън в Мейн, до новоизбраните демократи от традиционно консервативни щати, които могат да бъдат добър баланс или обратното – да не могат да се разбират взаимно.
Важно е да се отбележи, че мнозинството от избраните демократи са подчертано умерени и центристи. Групата по интереси на демократите Blue Dog Coalition, които поддържат центристки възгледи, обяви, че 14 нейни членове са избрани в Камарата. Други центристки групи, като New Democrats и Problem Solvers, също са увеличили представителството си.
Предизборна реклама на Джеймс Таларико, концентрирана върху достъпни цени и политически диалог за работа в името на хората
За повечето рационални хора беше ясно, че ерата „Тръмп“ ще има печален край, въпросът беше колко и на каква цена – както за САЩ, така и за света. Онези, които все пак понякога допускаха, че обратното е възможно, по-скоро се надяваха, че грешат за доброто на всички. В тази рубрика и преди сме си задавали въпроса какво ще се случи с партията, която избра да се идентифицира с един-единствен човек, след като неизбежните му човешки и политически провали доведат до отлив на избиратели.
В часовете след загубата Джей Ди Ванс показа една възможна посока, като дипломатично се дистанцира от президента, същевременно успя да го цитира и да поеме някаква отговорност за загубата. Много виждат в бившия сенатор от Охайо новото лице – досега на тръмпизма, но оттук нататък може би на републиканизма.
Ванс обвини войната в Иран за загубата. Но в щаба на президента от месеци е било ясно, че прогнозите не са добри – и нито президентът, нито партията са сменили курса, за да чуят проблемите на избирателя; напротив – само преди седмици президентът Тръмп каза, че няма проблем да се плащат по-високи цени за горива, ако петролните компании са на печалба. Арогантността, безпринципността и отявлената корупция са не по-малко решаващи за загубата на партията, която от десетилетие разчита на пропаганда, черен пиар и негативна кампания, за да прави политика. Вероятно ще отнеме повече от две години на републиканците да се разделят с този бранд.
Икономиката, състоянието на демокрацията, имиграцията, здравеопазването, външната политика и престъпността са сред приоритетите на избирателите, гласували на тези избори. Мнозинството от тях казват, че Тръмп е влошил икономическата обстановка. 38% заявяват, че са гневни относно състоянието на държавата, а 37% са недоволни. На 8 от 10 гласуващи инфлацията е причинила тежки или умерени проблеми. 74% от запитаните казват, че войната в Иран е била сред основните фактори за кого ще гласуват; 63% смятат, че е било грешка САЩ да атакуват.
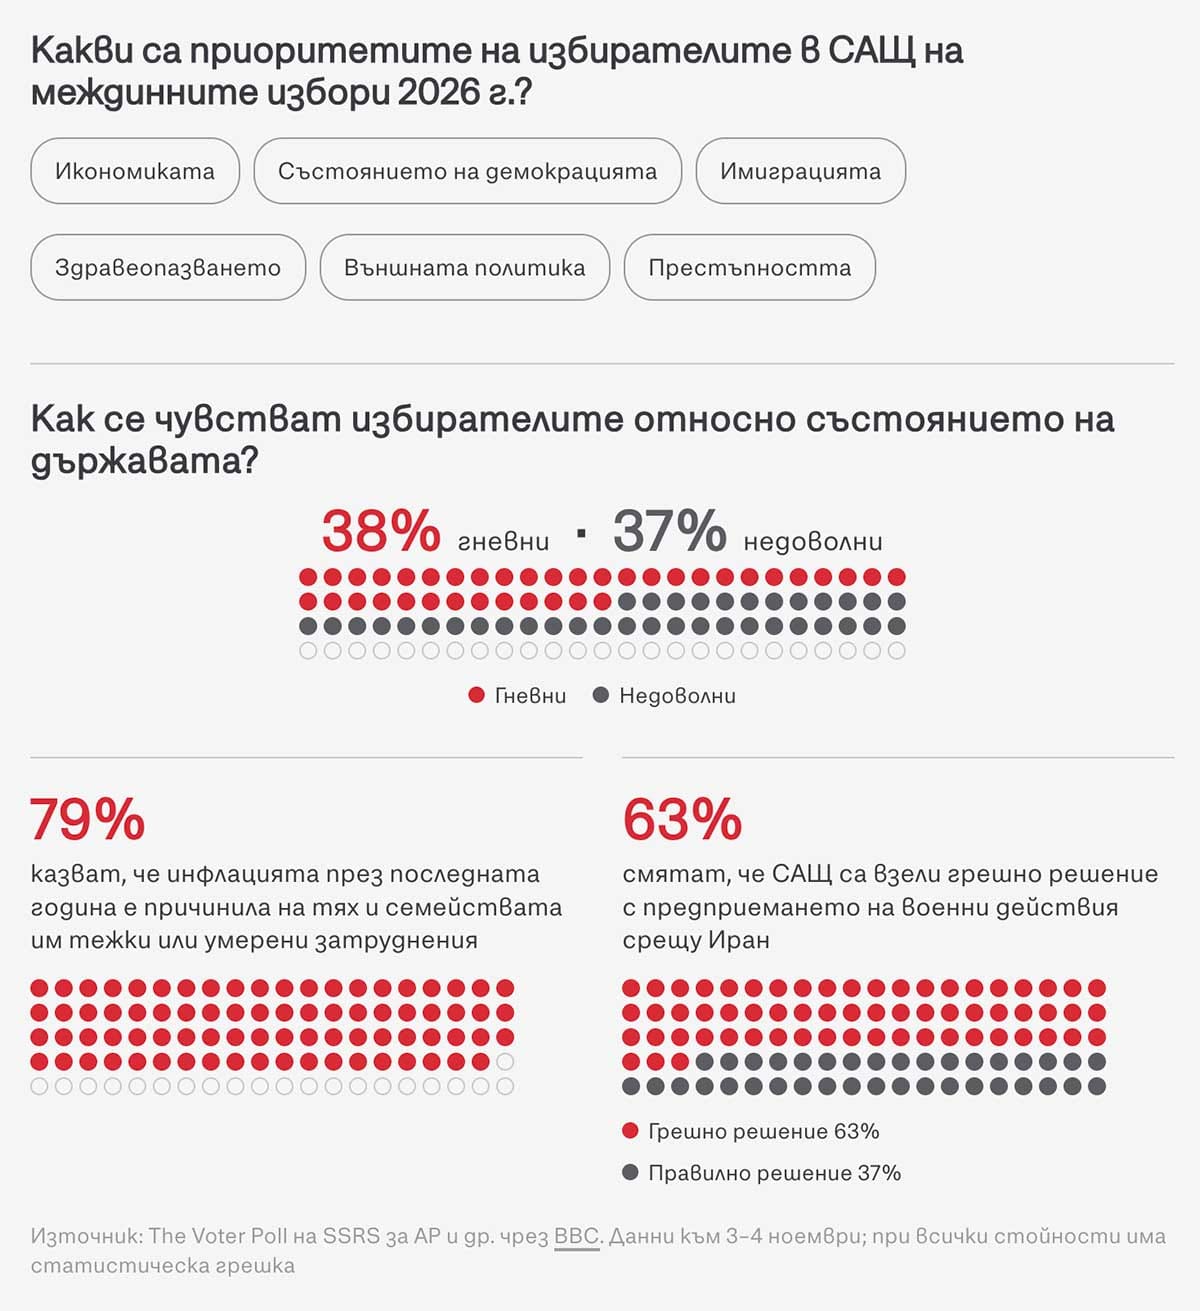
Според проучване на „Галъп“ разпределението на благата и концентрацията на капитал също са сериозен проблем за избирателите. Войната на Израел в Палестина също е посочена като фактор, а вече ви разказахме за безогледните строежи на центрове за данни, които са обединяващ фактор на недоволство в идеологическия спектър. Разделенията кой какво смята за важно, са очевидни между демократи и републиканци и не на последно място са резултат от медийните балони; консервативният е доказано наситен с дезинформация, но множество крайнолеви източници също разпространяват дезинформация и/или са податливи на манипулации.
Как ще се държи един своенравен, нарцистичен президент през идните две години, в които ще бъде принуден да се подчинява на волята на народа отново чрез демократични механизми? Ще успеят ли демократите да действат достатъчно бързо и ефективно, за да има осезаема промяна и да не изгубят инерцията? Ще се радикализират ли последователите на Тръмп, или ще се оттеглят от него? Каква посока ще изберат републиканците? Какъв обрат ще търси външната пропаганда, която цели да задълбочи и изостри вътрешнополитическото напрежение в САЩ, за да ги отслаби на световната сцена? Ще успеят ли демократите да прекратят подкрепата за Израел в Газа? Каква ще е позицията спрямо Украйна?
Отговорите на някои от тези въпроси ще се опитаме да дадем в следващите бюлетини. За останалото – ще покаже само времето.
Post Syndicated from Explosm.net original https://explosm.net/comics/smoke
New Cyanide and Happiness Comic
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/egJHiWIJz6M