AI coding agents on Amazon EC2 Mac: How Cognition scales Devin for macOS

Post Syndicated from Adam Hesch original https://aws.amazon.com/blogs/architecture/ai-coding-agents-on-amazon-ec2-mac-how-cognition-scales-devin-for-macos/

When the Cognition team set out to give Devin, their AI software engineer, the ability to build Apple apps, they ran into a basic requirement: Devin needed a Mac. The process of building, testing, and signing apps for iPhone, iPad, and Mac requires both Apple hardware and macOS, regardless of who (or what) writes the code, which was not supported until a couple months ago. To give Devin access to a Mac development environment, Cognition now runs macOS environments on Amazon Elastic Compute Cloud (Amazon EC2) Mac instances. With access to cloud-based Macs, Devin can build an iOS app, run it in the iOS Simulator, and check how it behaves all before it hands back a merge-ready change.

Within six weeks of launch, nearly 1,000 organizations were running Devin on macOS, according to Cognition. Cognition starts a fresh macOS virtual machine (VM) for each Devin session in under a minute, using a fleet of EC2 Mac hosts across six AWS Regions. By Cognition’s estimate, that startup time puts customers into a working macOS environment 15–20 times faster than setting up a Mac host themselves.

This post explains why Devin needed its own Mac, how Cognition built Devin workspaces on EC2 Mac, and how to plan a macOS fleet for AI agents or automated testing.

Why an AI coding agent needs its own Mac

Prior to this launch, Devin Cloud ran sessions only on Linux and Windows VMs. Devin could write Swift code and syntax in those sessions, but without macOS and Xcode it couldn’t run or test the app, so it depended on a customer’s continuous integration (CI) system or the customer’s own Mac fleet to build and test. Even then, simply having a successful build doesn’t show whether the app behaves correctly. One example of testing behavior is where an iPhone game is designed to resume where the player paused it, even after the app closes; in order to check that behavior, a software development agent has to play the game, pause it, quit, relaunch, and confirm the saved state.

You can virtualize macOS, but a Devin workspace needs more than just a bootable virtual operating system environment. Cognition needed each macOS workspace to provide the same properties as its other cloud workspaces:

  • A disk that keeps the work of a session, so an idle session doesn’t keep a VM running.
  • Network access that follows the access rules of the session.
  • A development environment that is ready before Devin starts.
  • A way for both the user and Devin to see and operate the running app.

Why Cognition chose AWS

Cognition required macOS machines to scale Devin beyond Linux and Windows, but sought to avoid the overhead of buying, racking, and maintaining physical Mac computers. The following properties of EC2 Mac shaped the Cognition design:

  • Apple silicon hardware in the cloud: Each EC2 Mac instance is a physical Mac mini or Mac Studio attached to the AWS Nitro System, so Cognition can run the Apple Virtualization framework on EC2 Mac the same way it would on an on-premises Mac.
  • Capacity through an API: Cognition allocates Dedicated Hosts and launches Mac instances with the Amazon EC2 API, instead of ordering and shipping machines.
  • Regions around the world: EC2 Mac is available in multiple AWS Regions, and Cognition runs in six of them.
  • Standard AWS networking and storage: Mac instances run in an Amazon Virtual Private Cloud (Amazon VPC) and boot from Amazon Elastic Block Store (Amazon EBS) volumes, so Cognition manages them like other EC2 instances.

Solution overview

Cognition builds Devin macOS workspaces on EC2 Mac instances, which run as bare metal instances on Amazon EC2 Dedicated Hosts. Available with Apple silicon, these instances are built on Apple Mac computers and the AWS Nitro System.

Each EC2 Mac instance runs on its own Dedicated Host, which has a minimum allocation period of 24 hours, so Cognition separates the life of a Devin session from the life of a host. In Regions where they don’t have preallocated capacity, Cognition uses an Amazon EC2 Auto Scaling group to allocate and release Dedicated Hosts.

On each host in its fleet, a Cognition VM manager uses the Apple Virtualization framework to run macOS guest VMs from images that Cognition prepares and manages. Each bare metal EC2 Mac host runs two isolated Devin workspaces at a time, because the macOS Software License Agreement (SLA) (SLA) allows up to two additional copies of macOS in virtual operating system environments on each Mac, a limit macOS enforces. Idle Devin sessions release their VMs for other Devin sessions to use, so a singular host is able to serve multiple Devin sessions a day.

Figure 1 shows how one EC2 Mac Dedicated Host serves Devin sessions. The host runs a bare metal Mac instance in one of the six AWS Regions in the Cognition fleet, with one guest VM per active session. Each guest runs Xcode tools and the iOS Simulator with the app under test, plus a live view and an accessibility tree from accessibility-cli. The user’s browser exchanges video and input with the live view, and the Devin agent queries and acts on the accessibility tree.

On the host, the VM manager runs the guests with the Virtualization framework, while a snapshot process with a Network Block Device (NBD) frontend handles disk I/O for each guest and exchanges snapshots with snapshot storage. The Devin agent and snapshot storage also run on AWS as Devin Cloud services inside the same Region, with Devin sessions hosted on Amazon EC2 and snapshots stored in Amazon Simple Storage Service (Amazon S3) (Amazon S3). For networking, a user-space Ethernet gateway takes Ethernet frames from a guest and passes IP packets to macOS packet filter (pf) rules and proxies, which apply the session access rules and send allowed traffic to the internet.
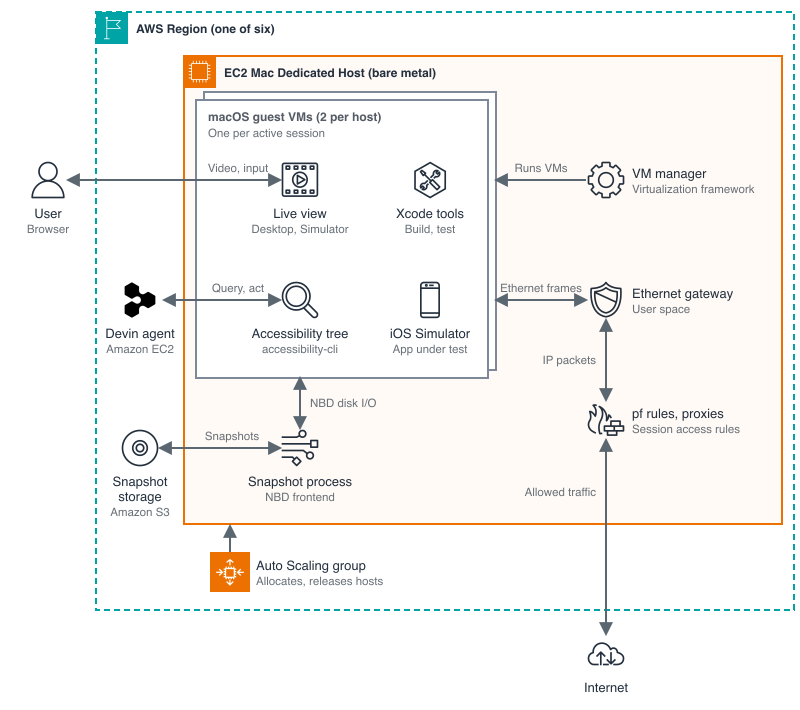
Architecture diagram. Inside an AWS Region, an EC2 Mac Dedicated Host runs two macOS guest VMs, one for each active Devin session. Each guest contains Xcode tools, the iOS Simulator with the app under test, a live view, and an accessibility tree. On the host, a VM manager runs the guests, a snapshot process connects guest disks to snapshot storage, and an Ethernet gateway passes guest traffic to packet filter rules and proxies that allow traffic to approved internet destinations. Also inside the Region, outside the host, the Devin agent on Amazon EC2 connects to the accessibility tree, snapshot storage in Amazon S3 holds session snapshots, and an Auto Scaling group allocates and releases hosts. Outside the Region, the user connects to the live view.

Figure 1: Devin macOS sessions on an Amazon EC2 Mac Dedicated Host

Keep session state with disk snapshots

Much of the work users do with Devin Cloud is asynchronous, and an idle session doesn’t need a running VM, so Cognition leverages the same snapshot system for macOS as its Linux VMs. The snapshot system runs as a separate process on the host and handles the VM’s disk reads and writes. Because the guest operating system sees only an ordinary virtual disk, the guest doesn’t need to know about snapshots.

On Linux, Cognition connects VMs to this storage process with vhost-user. The Virtualization framework doesn’t support vhost-user, but it does support NBD attachments, so Cognition added an NBD frontend to its snapshot system and kept the same storage design behind the new frontend. When a guest shuts down, the storage process keeps running to persist pending writes and upload the updated snapshot. The VM manager waits for the upload to finish before it completes cleanup, so stopping a session doesn’t interrupt the work that saves it.

Cognition reports that about 90% of sessions give up their Mac VM when idle and resume from a snapshot in seconds. On average, a session frees and reclaims its VM multiple times, so Mac capacity goes to active work, not idle sessions.

Apply network access rules with a user-space Ethernet gateway

Devin Cloud applies the access rules of each session to outbound traffic and blocks access to protected host infrastructure. The Virtualization framework offers three ways to connect a guest to the network: bridged networking, network address translation (NAT), and a file-handle attachment, which exchanges raw Ethernet frames over a local Unix datagram socket. NAT needs the least setup, but the Apple implementation also manages rules in pf, the macOS packet filter. Because Cognition also uses pf for its network controls, the two systems raced to configure the same filter.

Cognition chose the file-handle attachment instead and built its own Ethernet gateway to run in user space on the host, giving each Mac VM a separate gateway and its own session policy enforcement. Each Mac VM has its own gateway and its own session policy enforcement. The gateway answers Address Resolution Protocol requests from the guest and validates Ethernet addressing. It also checks that the source IP address of each packet matches the address assigned to the guest. The gateway then passes accepted IP packets into a tunnel interface on the host, where pf rules and proxies route the traffic and apply the access policy of the session.

Prepare guest images before the first boot

A Devin workspace needs more than a fresh macOS install: a user account, a usable desktop, Xcode tools, and the permissions Devin needs to observe and control apps. A fresh install asks for permissions such as accessibility and screen recording in dialogs, and each dialog would block Devin until a person approved it.

To avoid those dialogs, Cognition mounts the guest image disk on the host and prepares its state directly, creating the user and updating the macOS internal configuration databases so the permissions are in place before the guest boots. Cognition then boots the prepared image to install the remaining developer tools, verify Xcode, warm up the iOS Simulator, and let Spotlight indexing and other background setup finish. Cognition also turns off background services development sessions don’t need. With all this preparation done ahead of time, a new session can start building and testing as soon as its VM starts.

Give users a responsive live view of the app

Users can watch the macOS desktop in a Virtual Network Computing (VNC) view and their app in a new iOS Simulator pane in the Devin session. From either view, users can also try the app themselves and take control when they want.

Figure 2 shows a recorded Devin session from Cognition, in which Devin builds a 3D iPhone game and tests it in the iOS Simulator while the session’s Computer pane shows the macOS desktop.”

Figure 2: Devin builds and tests a 3D iPhone game on macOS. Video courtesy of Cognition

Two steps decide whether the live view responds fast enough for users to operate the app: capturing the screen and delivering the video. For the macOS desktop, ScreenCaptureKit, the Apple desktop capture API, supplies screen images from a limited pool of reusable buffers. When Cognition needs to keep the last captured image, it keeps its own copy instead of holding a pooled buffer, because holding a buffer while the screen is idle can delay the next screen change.

After capture, the desktop and Simulator video is encoded, sent to the user’s browser, and displayed. When one stage can’t keep up, frames wait between stages, and the stream can look smooth while it shows an old state of the app. In the iPhone game example, a user might press Pause and still see the game move, because the viewer is still showing frames from before the press. To keep the view current, Cognition limits how many frames can wait between stages and doesn’t replay a stale backlog.

Because compressed video frames often build on earlier frames, dropping a frame can leave the frames after it impossible to decode. A keyframe doesn’t depend on earlier frames, so the decoder can start fresh from it. When the Simulator stream falls behind, it restarts from a recent keyframe or asks for a new one and skips the missed frames. Keyframes are part of the compressed video stream, so they’re separate from the screen images Cognition copies at capture.

Let Devin operate native apps through the accessibility tree

Like users, Devin needs to see and operate the app, and it also needs an efficient way to check the result of each action. Devin does this through computer use, which in its simplest form takes a screenshot, has a model find a control in the image, clicks it, and takes another screenshot. This loop is slow and costly across the many pause, quit, and relaunch paths that Devin tests compared to web apps, where browser automation is more efficient. This is because the browser exposes the page structure, so Devin can find a named button or read a field’s value without working from pixels.

Native macOS apps and apps in the iOS Simulator run outside the browser, but they expose a structure of their own: the accessibility tree. Built for assistive technologies, the tree describes each control by its role, name, value, state, and relationships to other controls. Cognition exposes this tree to the Devin computer-use tool, so Devin can confirm that a control is a Resume button instead of guessing from pixels. Devin queries for a control, acts on the reference the query returns, and then reads the tree again to report what changed. The following exchange, adapted from Bringing macOS to Devin, shows a query for a Resume button and the press that follows.

{ "action": "query", "target": "ios", "role": "button", "name": "Resume" }

The shortened result lists a reference, the control’s role, its accessible name, and the actions it supports.

@i17 button "Resume" {press}

Using that reference, Devin then presses the control.

{ "action": "act", "target": "ios", "reference": "@i17", "operation": "press" }

Cognition built these capabilities on the open source accessibility-cli project from Dioxus, which is now part of Cognition. The project provides accessibility, input, and screen capture building blocks, and Devin turns them into the observe, reference, and act loop shown here. Even with the accessibility tree, Devin still relies on screenshots to check how the app looks. In the game example, a closed pause menu doesn’t prove the game restored the player’s position, because the app might draw gameplay directly instead of describing it in the tree.
Results

Cognition launched macOS support for Devin on September 15, 2026, and nearly 1,000 organizations were running Devin on macOS within six weeks. Devin no longer needs a customer’s CI system or Mac computers to build and test Apple apps, because it now builds, runs, and verifies iPhone, iPad, and Mac apps in its own cloud workspace. From that workspace, Devin also uploads builds to TestFlight, the Apple beta testing service.

“With Amazon EC2 Mac, we gave Devin macOS environments in the cloud, unlocking iOS and macOS development. Now customers can hand Devin platform-specific tasks such as building and testing iOS applications, without anyone managing Mac hardware. Our mac-m4pro.metal and mac-m4.metal fleet spans six regions, and we can mint fresh macOS VMs for Devin in under a minute.”

— Evan Almloff, Member of Technical Staff, Cognition

Wispr, which makes the Wispr Flow voice dictation app, uses Devin for macOS to test its iOS app end to end.

“At Wispr, a big part of testing our iOS app is making sure recording and transcription work end to end. The biggest blocker for us was end to end testing with Audio and Keyboard extension. With Devin’s macOS support, the pace of development has accelerated and it has given us more confidence in shipping features and triaging bugs. The velocity unlock is huge and cut down code review time by 70% and improved our velocity by nearly 2x.”

— Sumit Oberoi, Lead iOS Engineer, Wispr

Plan your own macOS fleet on EC2 Mac

The following points from the Amazon EC2 User Guide affect how you design a macOS fleet:

  • Each Dedicated Host runs one Mac instance, and you can release a host only after its 24-hour minimum allocation period.
  • You can share Dedicated Hosts with other AWS accounts or within an organization in AWS Organizations using Cross-account Amazon EC2 Dedicated Host sharing.
  • Mac instances are available as On-Demand Instances, and you can lower their cost with a Savings Plan.
  • Mac instance types are available in specific Regions, so check Amazon EC2 instance types by Region before you plan capacity.

Conclusion

Cognition gave Devin its own cloud Mac by running a fresh macOS guest VM for each session on Amazon EC2 Mac bare metal hosts. Disk snapshots, a user-space Ethernet gateway, prepared guest images, and accessibility-based control turn each VM into a workspace where Devin can build, run, and verify Apple apps.

Get started with Amazon EC2 Mac instances, and read Bringing macOS to Devin for more detail on how Cognition built Devin for macOS.

Resources


About the authors

Adam Hesch

Adam Hesch

Adam is a Partner Deployed Engineer at Cognition, focused on agentic AI and cloud partnerships. Before Cognition, Adam spent seven and a half years at AWS, most recently as Lead Solutions Architect for Federal Partners. A former US Navy officer, Adam holds a B.S. in computer science from the United States Naval Academy and an MBA from Indiana University Bloomington.

Sahin Olut

Sahin Olut

Sahin is a Member of Technical Staff at Cognition, focused on platform and systems engineering. Before Cognition, Sahin spent five years at Rippling, most recently as a Principal Software Engineer. Sahin holds a master’s degree in computer science from the University of North Carolina at Chapel Hill, with research on machine learning for medical image registration.

Evan Almloff

Evan Almloff

Evan is a Member of Technical Staff at Cognition and a maintainer of Dioxus, a cross-platform UI library for Rust. Evan joined Cognition with the Dioxus team and is interested in cross-platform UI and private, controllable AI.

Hadrien Almela

Hadrien Almela

Hadrien is a Senior Frontier AI Account Manager in the AWS Startup team, helping top AI startups build technical integrations and global go-to-market (GTM) partnerships. He has eight years of experience in the startup landscape.

Daniel Quang

Daniel Quang

Daniel is a Solutions Architect on the Frontier AI Startups team at AWS, where he helps the world’s largest and most strategic generative AI startups scale their infrastructure on the cloud. He holds a PhD in Computer Science from the University of California, Irvine, with a research focus on machine learning and bioinformatics.

Kyle Krall

Kyle Krall

Kyle is a Specialist Solutions Architect for Amazon EC2 Mac on the AWS Compute team, where he draws on his background in SRE and DevOps to help customers build and scale macOS workloads on AWS.

Christina Mitine

Christina Mitine

Christina is the Worldwide Go-to-Market Lead for Amazon EC2 Mac on the AWS Compute team. She works with customers of all sizes, from AI startups building coding agents to enterprises running CI/CD, to scale their macOS workloads on AWS. Outside of work, she enjoys playing tennis, hiking, reading, and traveling.

Announcing custom execution roles for AWS CloudFormation StackSets

Post Syndicated from Tanvi Ravindra Malali original https://aws.amazon.com/blogs/devops/announcing-custom-execution-roles-for-aws-cloudformation-stacksets/

With AWS CloudFormation StackSets, you can create, update, and delete stacks across many accounts and Regions from a single operation. By default, StackSets creates an execution role with AdministratorAccess in each target account, which requires no additional setup. With custom execution role templates, you can define the IAM role that StackSets uses in each member account instead.

This provides two capabilities. First, you can scope the execution role’s permissions to only what your workload needs. Second, service-managed stack sets can deploy templates that use nested stacks, macros, and transforms.

Note: Switching to a custom execution role does not remove the default AdministratorAccess execution role from member accounts. For true least-privilege access, delete the default role in each member account after you confirm the custom role works.

How it works

When you create or update a stack set with an execution role template, StackSets validates it and stores it. For each target member account, StackSets then deploys the template as a small bootstrapping stack that creates the IAM role. StackSets uses the name you passed in the ExecutionRoleName parameter for all subsequent operations. The StackSetExecutionRoleName output is used only to validate that the role the template provisioned matches that name.

The bootstrapping stack is created once per member account, always in the home Region of the partition (us-east-1 for commercial, cn-north-1 for China). It is named stacksets-exec-role-stack-<region>-<stackset-id>-<short-uuid>. From that point on, every create, update, and delete operation StackSets runs in that member account uses your custom role.

Templates with nested stacks, macros, and transforms

With a custom execution role, service-managed stack sets can deploy workload templates that use nested stacks (AWS::CloudFormation::Stack), CloudFormation transforms (such as AWS::Serverless-2016-10-31), and custom macros. Previously, these features were not supported in service-managed stack sets.

This capability applies to the workload template you deploy with your stack set, not to the execution role template itself. The execution role template must still follow the requirements in the next section, including no nested stacks and no transforms.

For a workload template that uses transforms or macros, such as a SAM template, pass both CAPABILITY_NAMED_IAM and CAPABILITY_AUTO_EXPAND when creating the stack set:

aws cloudformation create-stack-set \
--stack-set-name my-sam-stack-set \
--template-body file://my-sam-template.yaml \
--permission-model SERVICE_MANAGED \
--execution-role-template-body file://execution-role-template.yaml \
--execution-role-name stacksets-exec-custom-my-role \
--capabilities CAPABILITY_NAMED_IAM CAPABILITY_AUTO_EXPAND

Prerequisites

Before you configure a custom execution role template, make sure:

  • Your StackSet uses the service-managed permissions model. Custom execution role templates are not supported with self-managed permissions.
  • Activate trusted access with AWS Organizations. This creates the AWSServiceRoleForCloudFormationStackSetsOrgAdmin service-linked role in your management account.
  • You have your management account ID available for use in the trust policy.

Execution role template requirements

Your execution role template must meet all four of the following requirements. If any requirement is not met, CreateStackSet or UpdateStackSet returns a validation error.

1. A single IAM role resource

The template must contain exactly one resource, and that resource must be of type AWS::IAM::Role. Templates with multiple resources or non-IAM resources are rejected.

Note: Name the role with the required prefix stacksets-exec-custom- (for example, stacksets-exec-custom-my-role). The service’s default execution role is named stacksets-exec-<hash>, so this prefix is what lets StackSets tell a custom role from a default one by name alone. Roles without this prefix fail validation. Use the same role name across all stack instances. Don’t vary it per account or Region.

2. A trust policy for the StackSets service-linked role

The IAM role must include an AssumeRolePolicyDocument that grants assume-role access to the StackSets service-linked role in your management account. The trust policy must contain exactly one Statement and exactly one AWS principal, in this format:

arn:aws:iam::<management-account-id>:role/aws-service-role/stacksets.cloudformation.amazonaws.com/AWSServiceRoleForCloudFormationStackSetsOrgAdmin

Replace <management-account-id> with your organization’s management account ID.

If your organization uses a delegated administrator account for StackSets, the trust policy must still reference the organization management account rather than the delegated administrator account.

You can optionally strengthen the trust policy with a condition on your organization ID:

AssumeRolePolicyDocument:
  Version: "2012-10-17"
  Statement:
    - Effect: Allow
      Principal:
        AWS: arn:aws:iam::123456789012:role/aws-service-role/stacksets.cloudformation.amazonaws.com/AWSServiceRoleForCloudFormationStackSetsOrgAdmin
      Action: sts:AssumeRole
      Condition:
        StringEquals:
          aws:SourceOrgID: o-exampleorgid

3. A required output

The template must define a CloudFormation output with the key StackSetExecutionRoleName, and its value must be the name of the IAM role created by the template. StackSets uses this output to validate that the role name the template provisioned matches the ExecutionRoleName you passed when you created or updated the stack set. If the output is missing or the key is misspelled, the template fails validation.

4. No nested stacks or transforms

The template must not include:

  • Nested stack resources (AWS::CloudFormation::Stack).
  • CloudFormation transforms, such as AWS::Serverless-2016-10-31 or custom macros.

A working example

The following least-privilege template creates an execution role scoped to S3 bucket operations on buckets matching a naming prefix, plus the CloudFormation actions StackSets needs to drive stack operations in the member account.

AWSTemplateFormatVersion: "2010-09-09"
Description: Custom execution role for CloudFormation StackSets
Resources:
  StackSetExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      RoleName: stacksets-exec-custom-my-role
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              AWS: arn:aws:iam::123456789012:role/aws-service-role/stacksets.cloudformation.amazonaws.com/AWSServiceRoleForCloudFormationStackSetsOrgAdmin
            Action: sts:AssumeRole
      Policies:
        - PolicyName: StackSetExecutionPolicy
          PolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Effect: Allow
                Action:
                  - s3:CreateBucket
                  - s3:DeleteBucket
                  - s3:PutBucketPolicy
                  - s3:GetBucketPolicy
                Resource: "arn:aws:s3:::amzn-s3-demo-*"
              - Effect: Allow
                Action: cloudformation:*
                Resource: "*"
Outputs:
  StackSetExecutionRoleName:
    Value: !Ref StackSetExecutionRole
    Description: Name of the execution role used by StackSets

This template is an illustrative example. The cloudformation:* permissions on all resources are the minimum StackSets needs to drive stack operations in each member account. Narrowing them below this can cause stack operations to fail. Adjust the S3 statement to match the resources your workload uses.

Replace 123456789012 with your management account ID. Using !Ref on the role returns the role name dynamically, so you don’t need to repeat it in the output.

Creating a StackSet with a custom execution role template

Supply the template to CreateStackSet in one of two ways:

  • ExecutionRoleTemplateBody – the template body as an inline string (JSON or YAML).
  • ExecutionRoleTemplateUrl – the Amazon Simple Storage Service (Amazon S3) URL of the template file.

Specify either one of these. If you provide both, the operation returns an error.

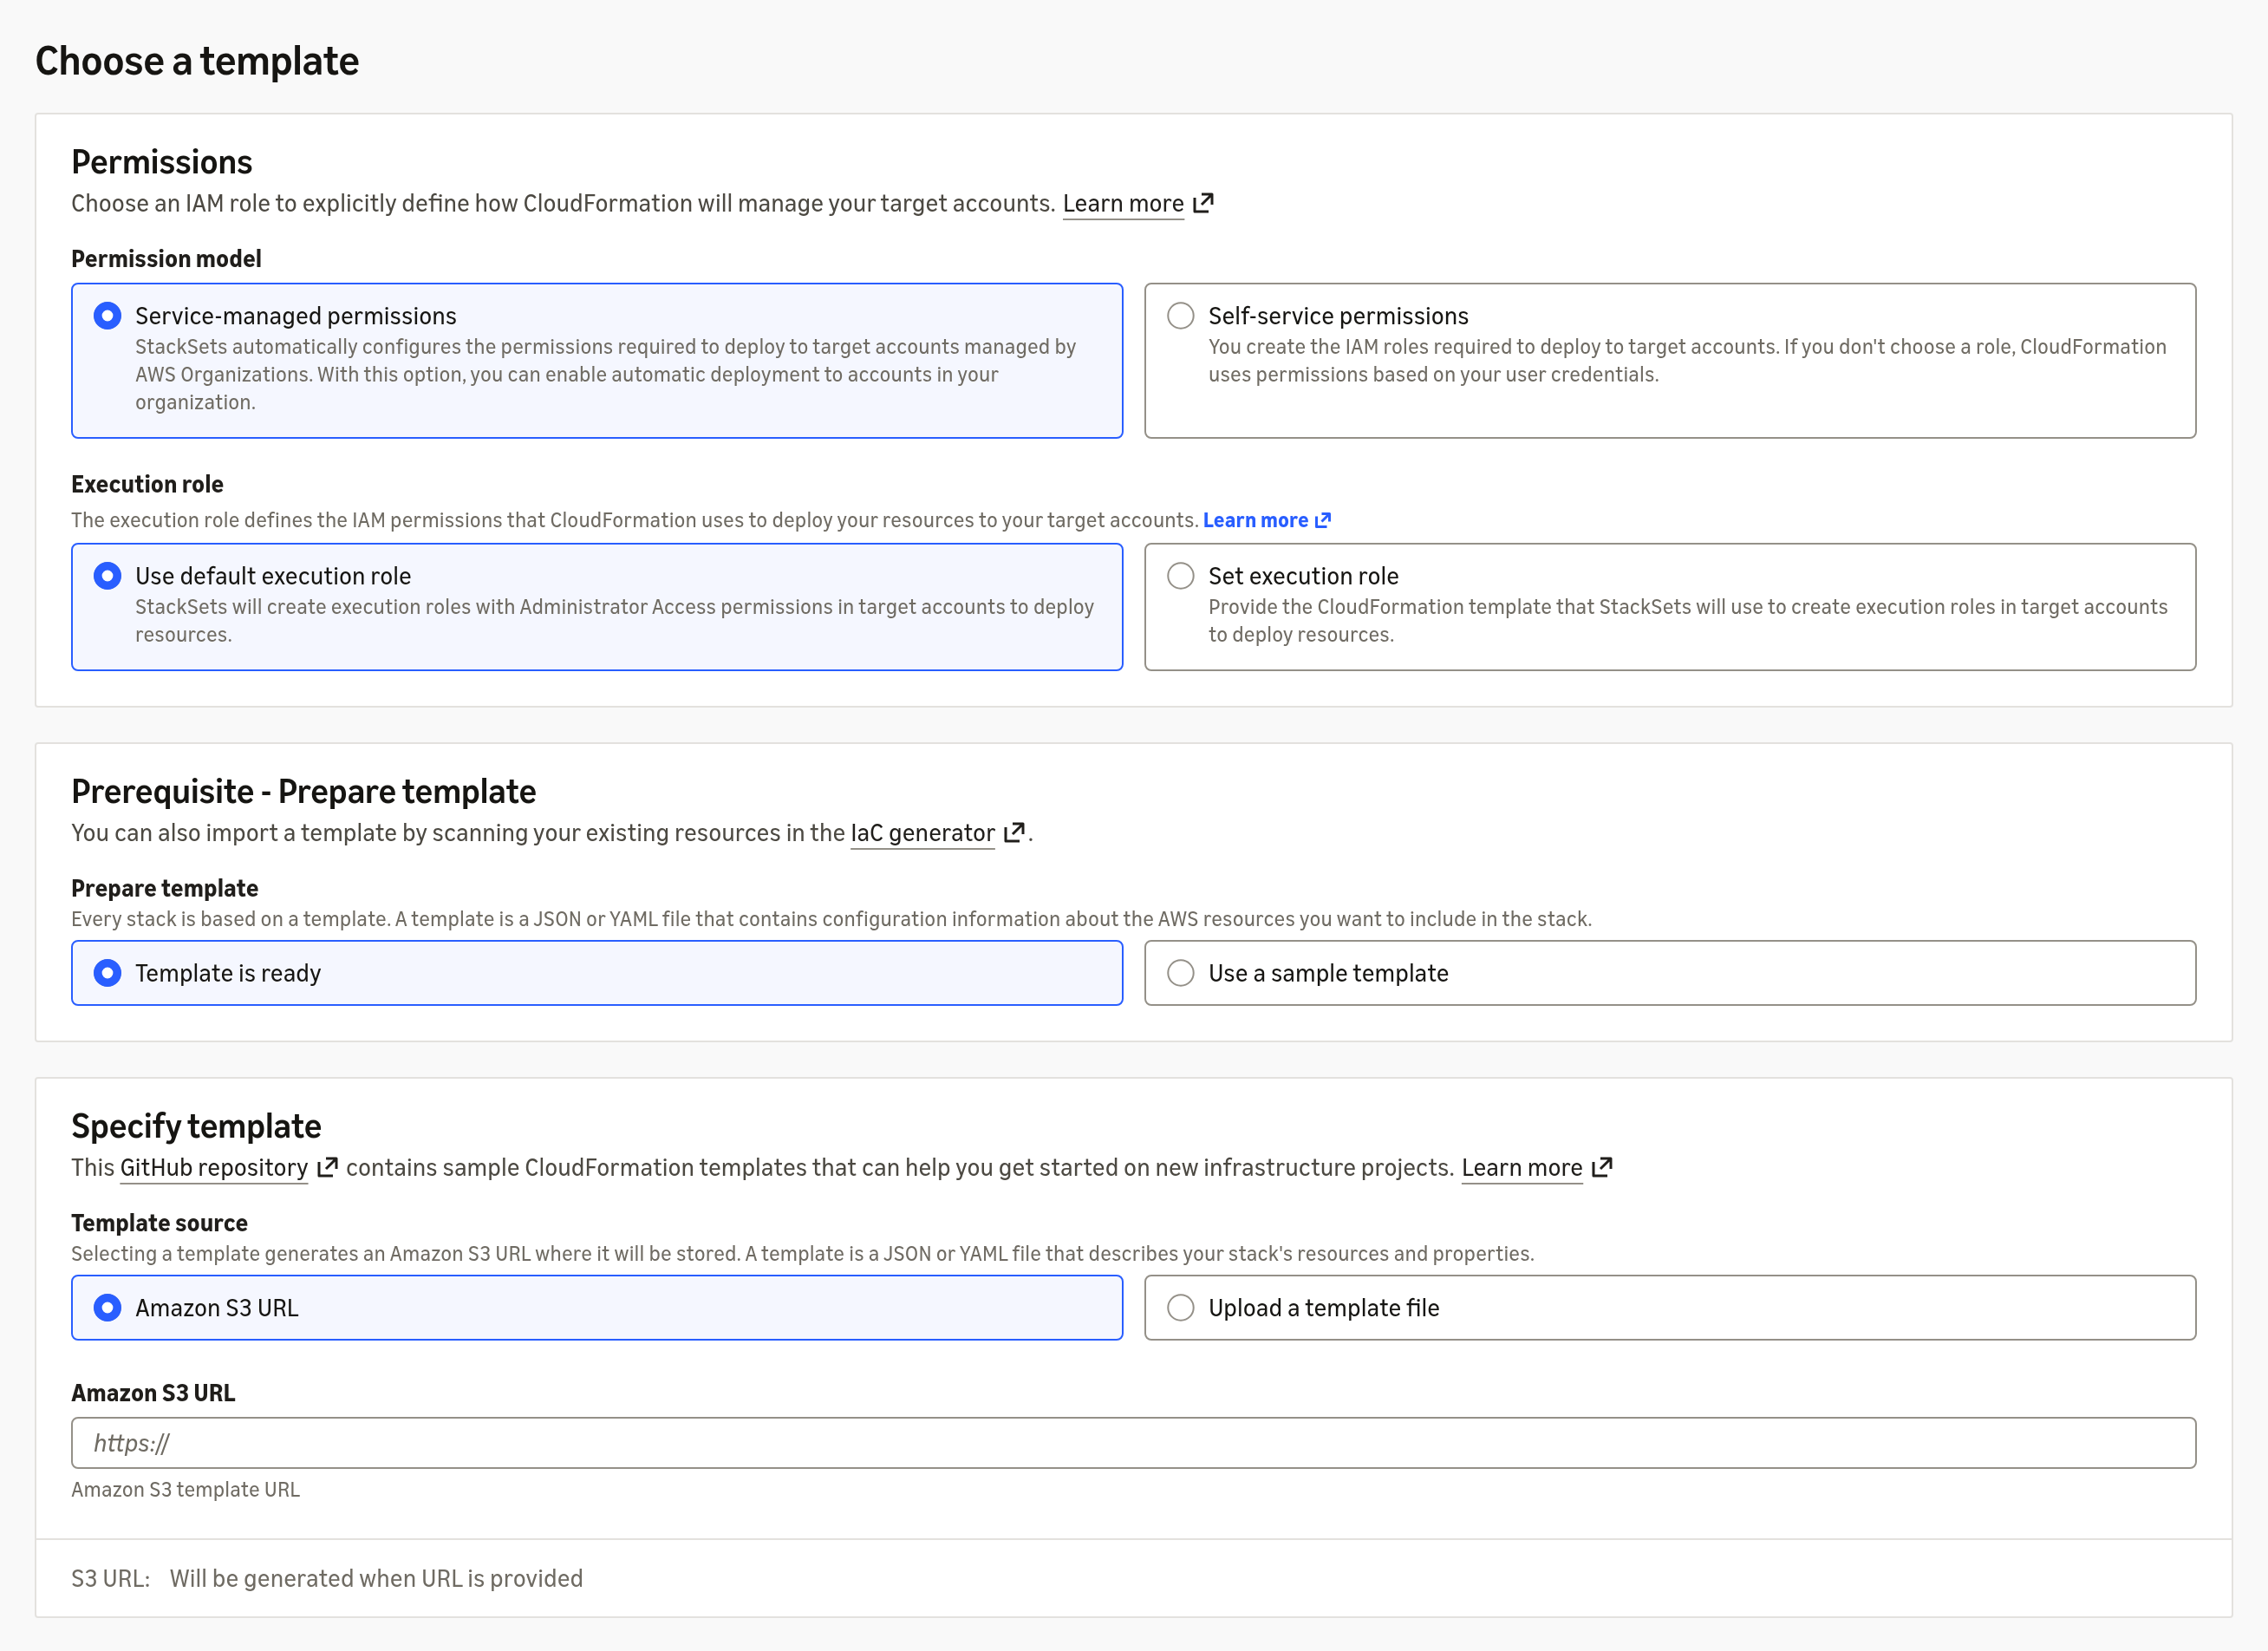
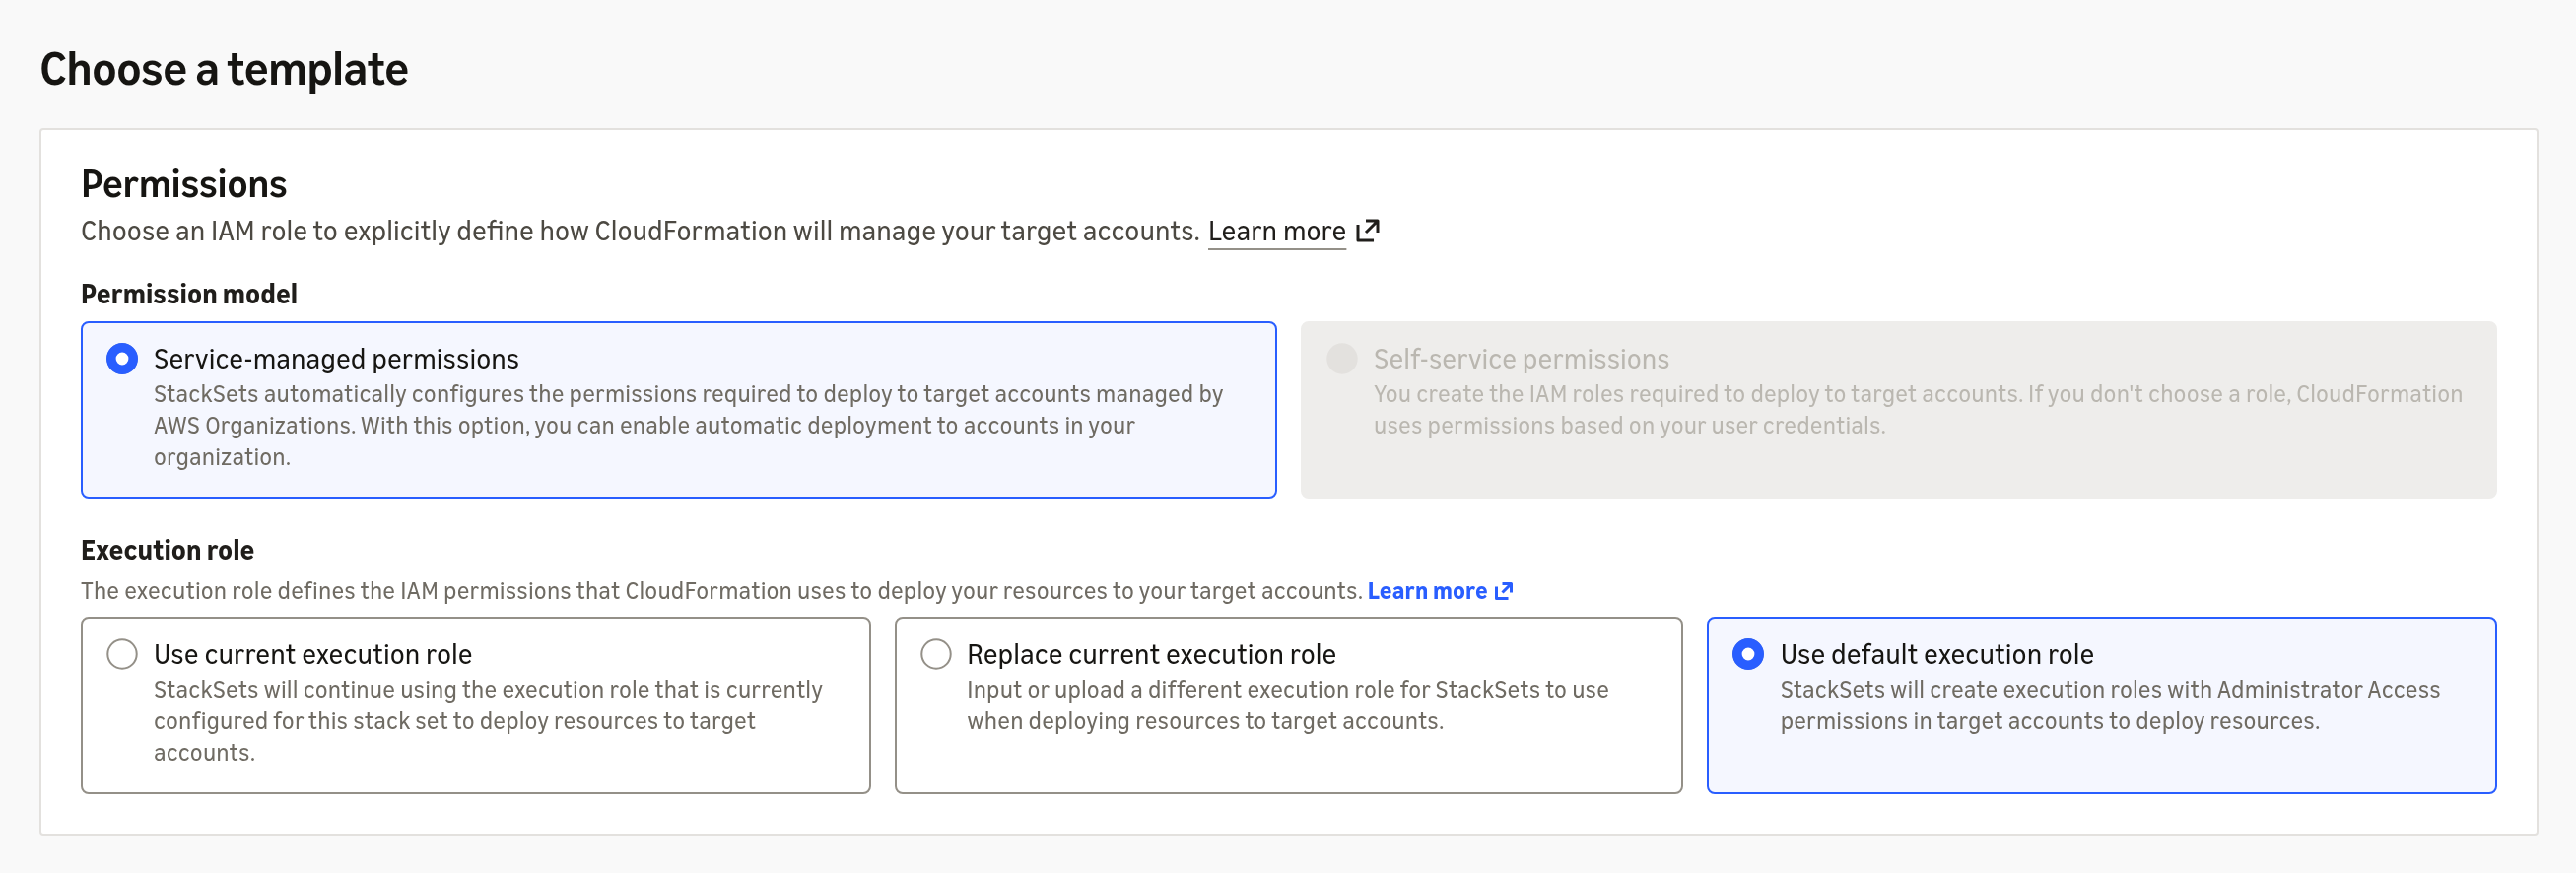
Console view of the StackSet creation wizard showing the custom execution role template options, with the default option selected.

Figure 1: Console view of the configurable options when creating a StackSet custom execution role

Using the AWS CLI

aws cloudformation create-stack-set \
--stack-set-name my-stack-set \
--template-body file://my-stackset-template.yaml \
--permission-model SERVICE_MANAGED \
--execution-role-template-body file://execution-role-template.yaml \
--execution-role-name stacksets-exec-custom-my-role \
--capabilities CAPABILITY_NAMED_IAM

The --execution-role-name value must match the RoleName in your execution role template, and it must start with stacksets-exec-custom-. StackSets validates this prefix and returns an error if it does not match.

Custom execution role templates always require CAPABILITY_NAMED_IAM. This flag acknowledges that the templates create named IAM resources. The execution role template always creates a named IAM resource, because it must use the required stacksets-exec-custom- prefix through an explicit RoleName. If your workload template also uses transforms (such as AWS::Serverless-2016-10-31) or macros, add CAPABILITY_AUTO_EXPAND as well. Capabilities apply at the stack set level and pass down to each stack instance.

With an S3-hosted template:

aws cloudformation create-stack-set \
--stack-set-name my-stack-set \
--template-body file://my-stackset-template.yaml \
--permission-model SERVICE_MANAGED \
--execution-role-template-url https://s3.amazonaws.com/amzn-s3-demo-bucket/execution-role-template.yaml \
--execution-role-name stacksets-exec-custom-my-role \
--capabilities CAPABILITY_NAMED_IAM

Note: If you use an S3 URL, your credentials must have read access to the S3 object. The URL can be in path style (https://s3.amazonaws.com/my-bucket/key.yaml) or virtual-hosted style (https://my-bucket.s3.region.amazonaws.com/key.yaml).

Using the CloudFormation console

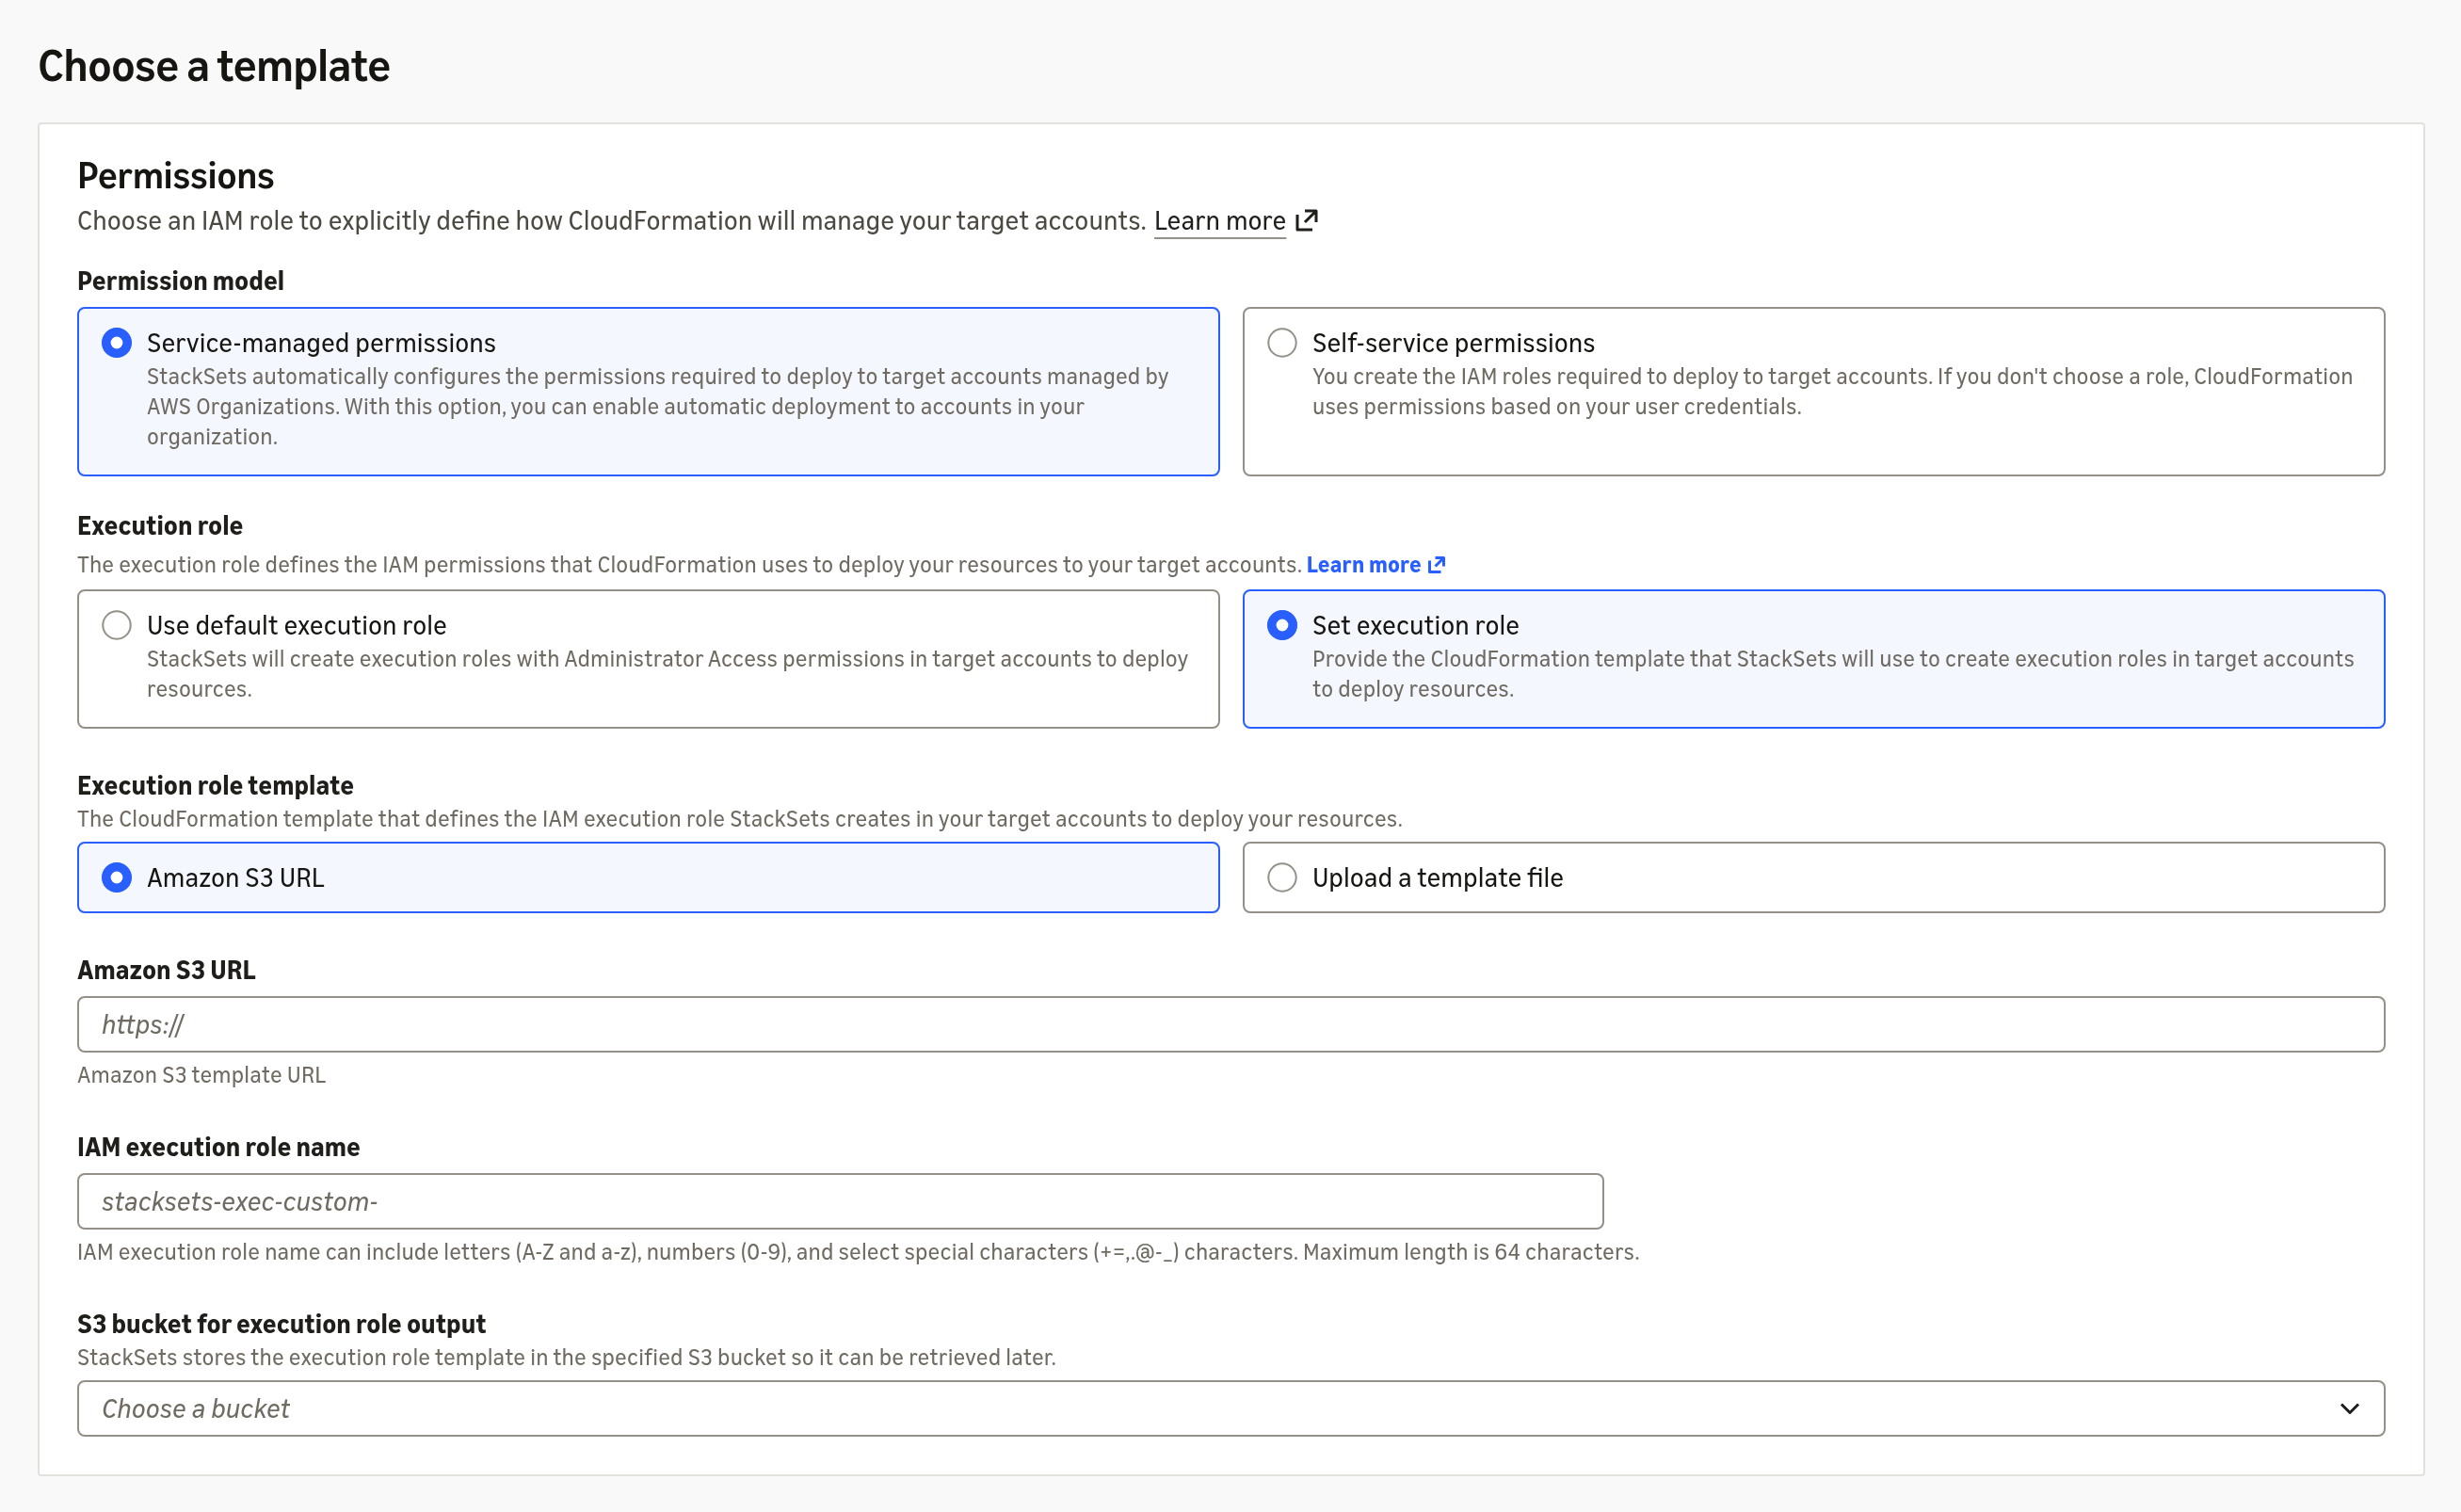
The create StackSet wizard defaults to Use default execution role, which is the AdministratorAccess role. To attach a custom execution role, select Set execution role and either paste an S3 URL or upload a local template file.

The console also asks for an IAM execution role name in a separate field. StackSets uses the name you enter in this field as the execution role name, not the RoleName value in the template. Make sure the name in the field still starts with the required stacksets-exec-custom- prefix.

StackSet creation wizard on the CloudFormation console defaulting to the AdministratorAccess execution role, with the Set execution role option available to add a custom role.

Figure 2: The StackSet creation wizard defaulting to the AdministratorAccess execution role, with the option to set a custom execution role

Updating the execution role template

To update the execution role template for an existing stack set, call UpdateStackSet with a new ExecutionRoleTemplateBody or ExecutionRoleTemplateUrl. The same validation requirements apply. When you update the execution role template, StackSets updates the role on every existing stack instance. You can’t specify deployment targets in the same call.

The --execution-role-name value is required only when you transition from the default execution role to a custom execution role. On subsequent updates to the execution role template, it’s optional.

aws cloudformation update-stack-set \
--stack-set-name my-stack-set \
--execution-role-template-body file://updated-execution-role-template.yaml \
--use-previous-template \
--capabilities CAPABILITY_NAMED_IAM

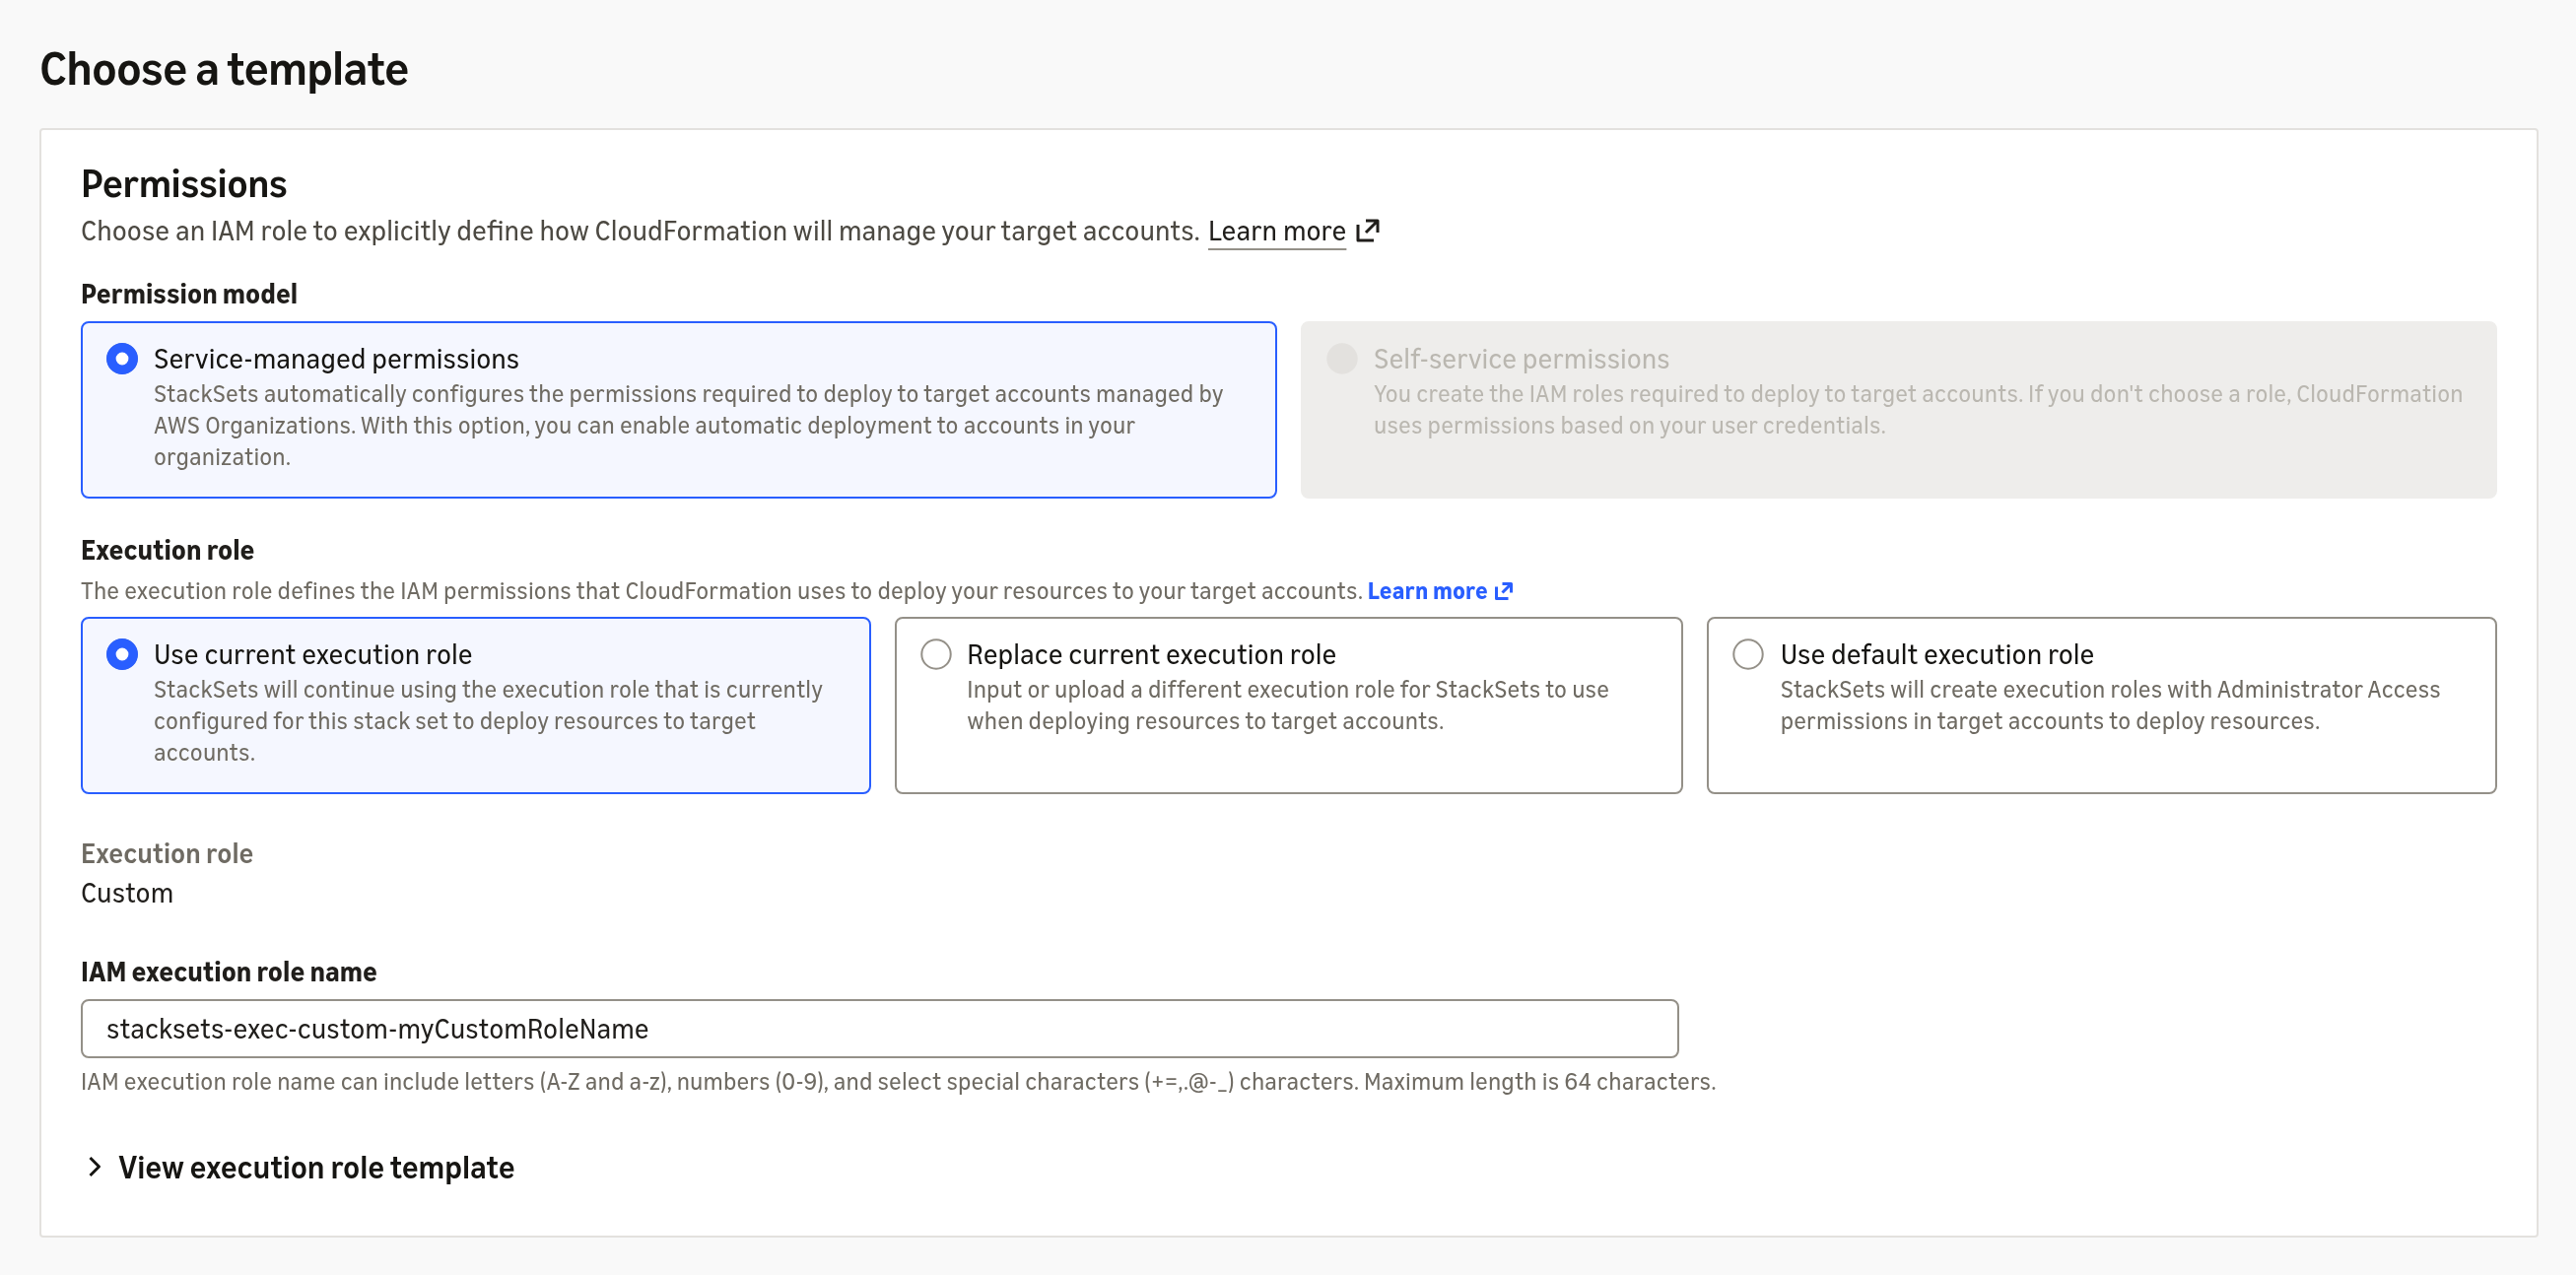
On the console, you can also change the execution role name without replacing the template. Select the Use current execution role tile to keep the existing template, and enter a new role name in the IAM execution role name field.

Console showing the Use current execution role tile selected, which keeps the existing template and changes only the execution role name.

Figure 3: Keeping the current execution role template and changing only the execution role name

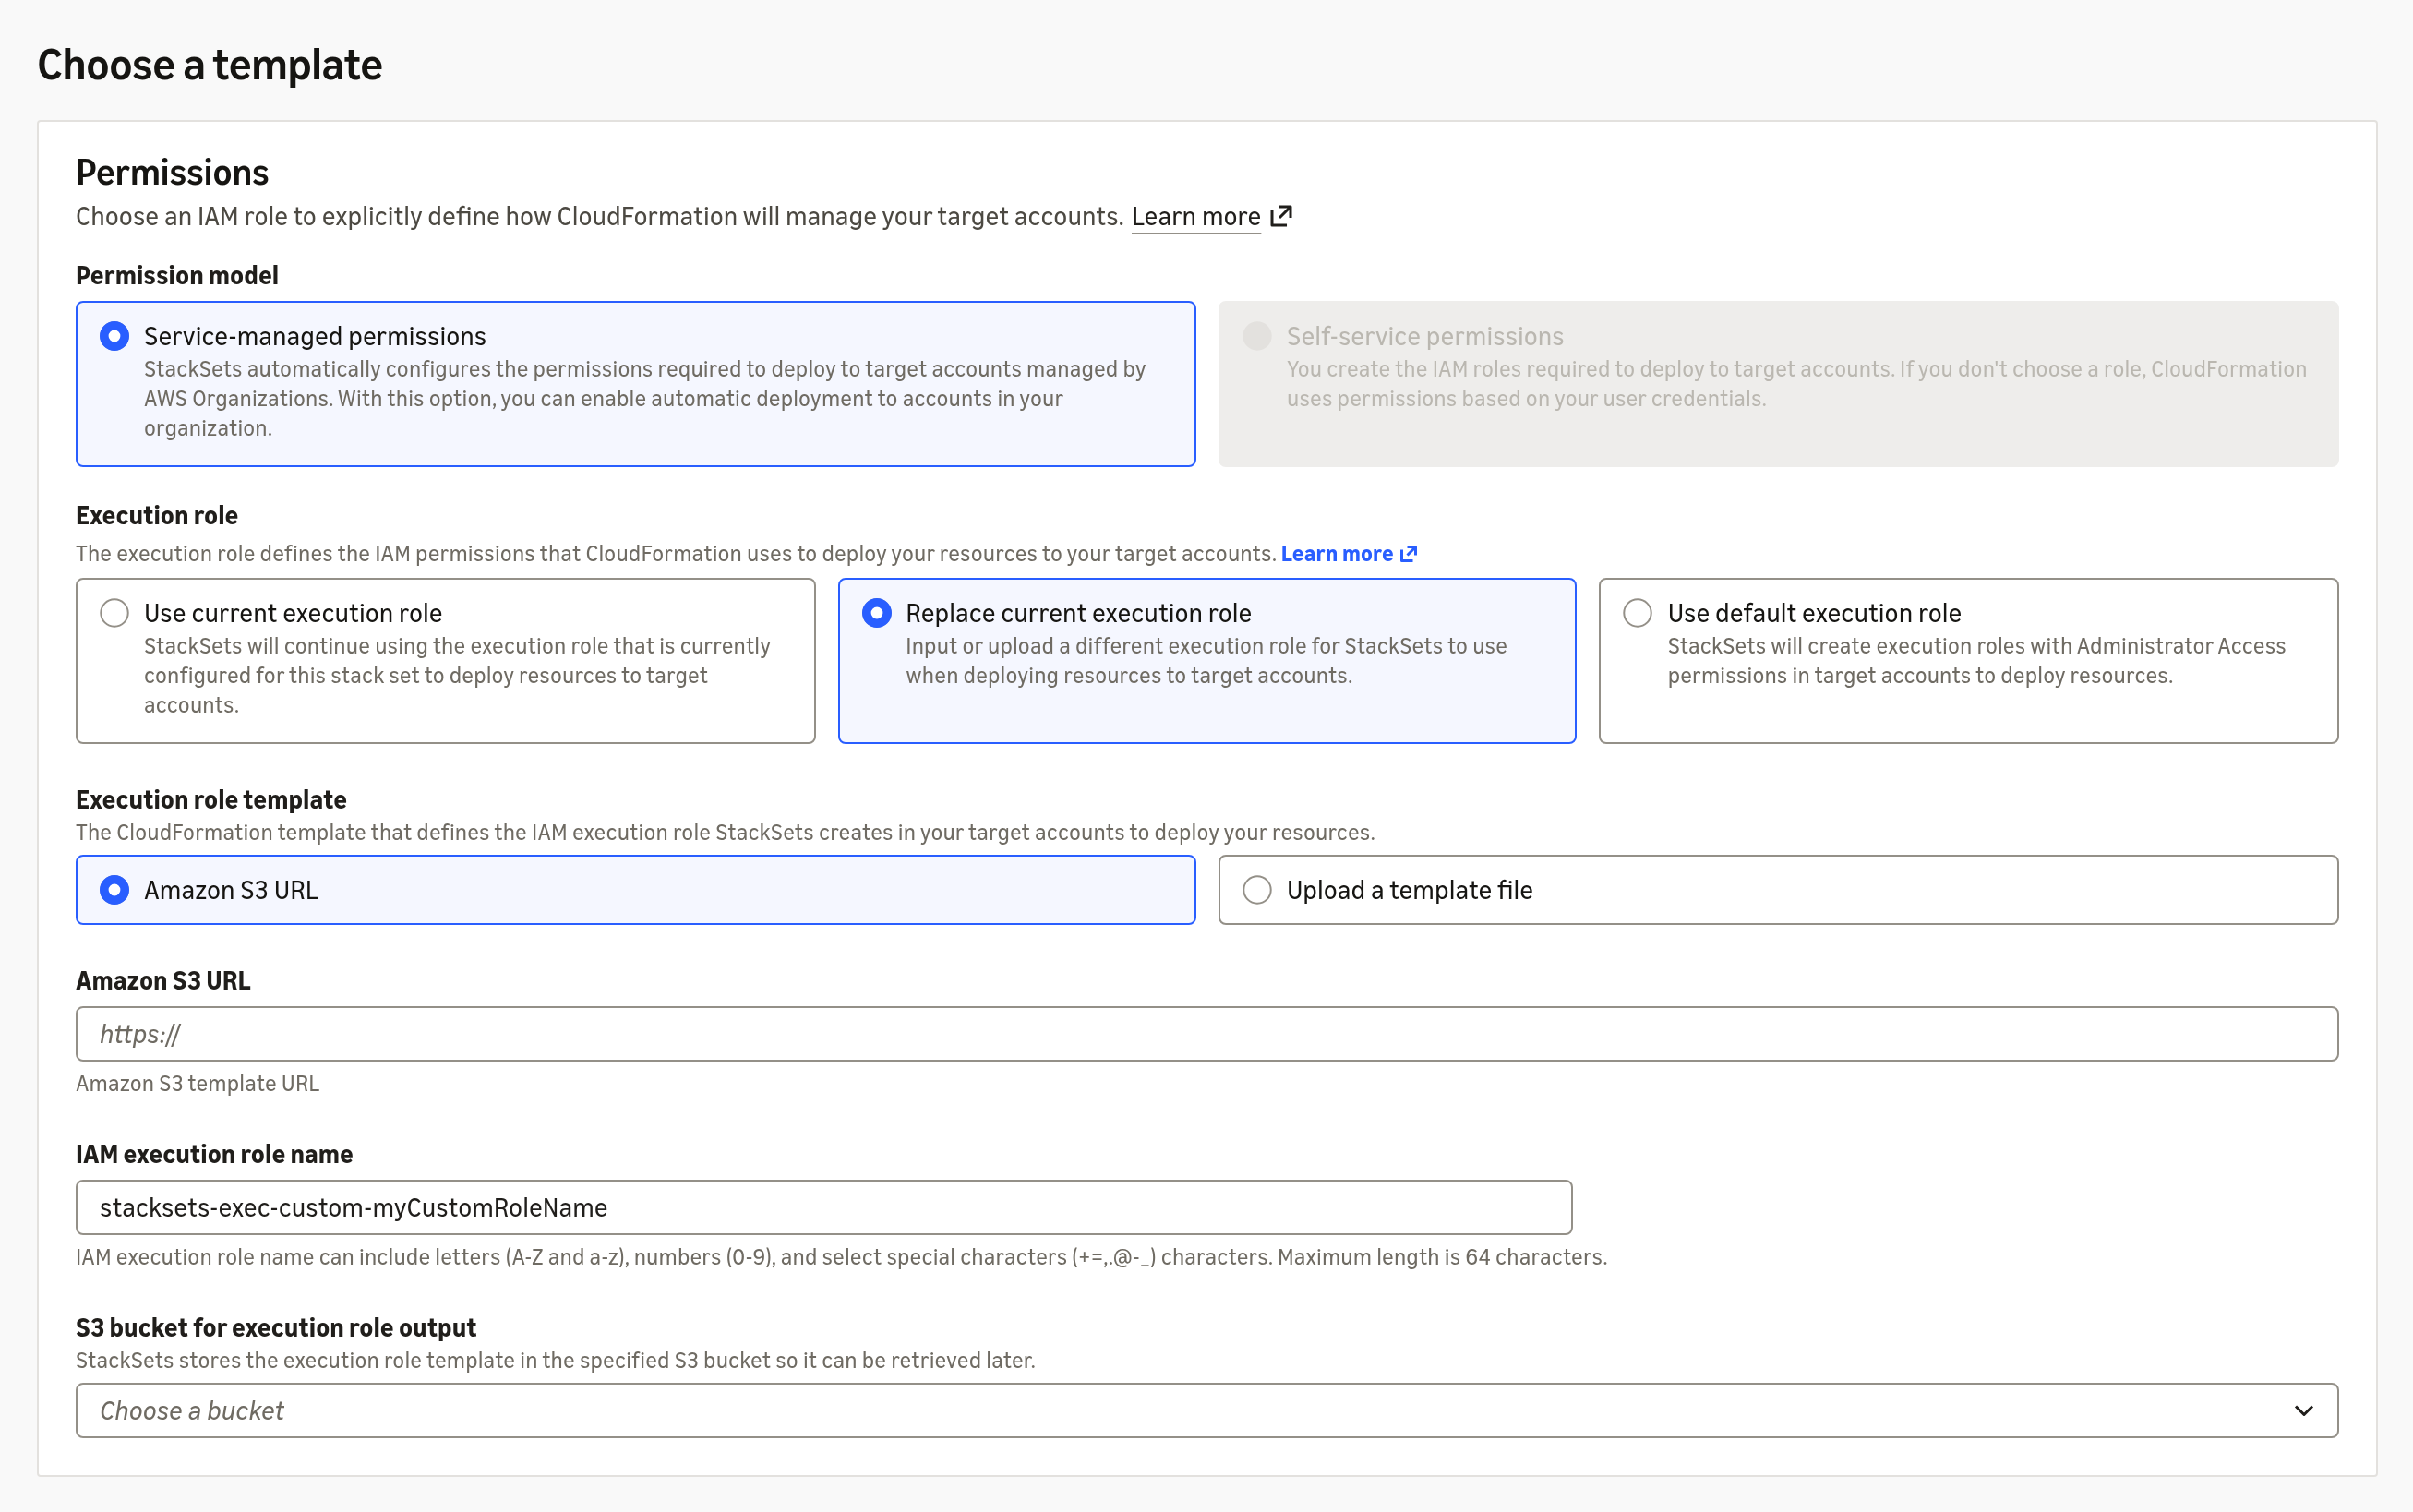
On the console, choose the Replace current execution role tile and either paste an S3 URL or upload a new template file.

Console showing the Replace current execution role tile selected, with options to provide an S3 URL or upload a local template file.

Figure 4: Replacing the execution role template by providing an S3 URL or uploading a local template file

Setting up an output bucket

StackSets always stores the validated execution role template in a service-owned bucket. You can also configure a bucket you own, and StackSets writes a copy of the template there. This is useful when you want direct visibility into the stored template.

To configure a custom output bucket:

  • Create an S3 bucket in the same Region as your stack set.
  • Update the bucket policy to allow the CloudFormation service principal (cloudformation.amazonaws.com) to perform s3:PutObject on the bucket path.
  • Pass the bucket name using --stack-set-output-bucket on create-stack-set or update-stack-set.
  • StackSets writes the copy at s3://<bucket>/aws-cloudformation-stacksets/<stack-set-id>/output.json, where the colons in the stack set ID are replaced by periods.

Reverting to the default execution role

To revert a StackSet to the default AdministratorAccess execution role, set UseAdminExecutionRole to true:

aws cloudformation update-stack-set \
--stack-set-name my-stack-set \
--use-admin-execution-role \
--use-previous-template

Reverting switches StackSets back to the default AdministratorAccess execution role, but it does not remove the custom execution role or its bootstrapping stack from member accounts. There is no automated cleanup today. Delete them manually in each member account if you no longer need them.

On the console, choose the Use default execution role tile during update.

Console view of the Use default execution role tile selected when updating a stack set.

Figure 5: Reverting to the default AdministratorAccess execution role by selecting the Use default execution role tile when updating a stack set

Viewing the current execution role template

Call DescribeStackSet to see the configured execution role template. If an output bucket is configured, the response includes the StackSetOutputBucketPath field, which points to the stored template in S3.

aws cloudformation describe-stack-set \
--stack-set-name my-stack-set

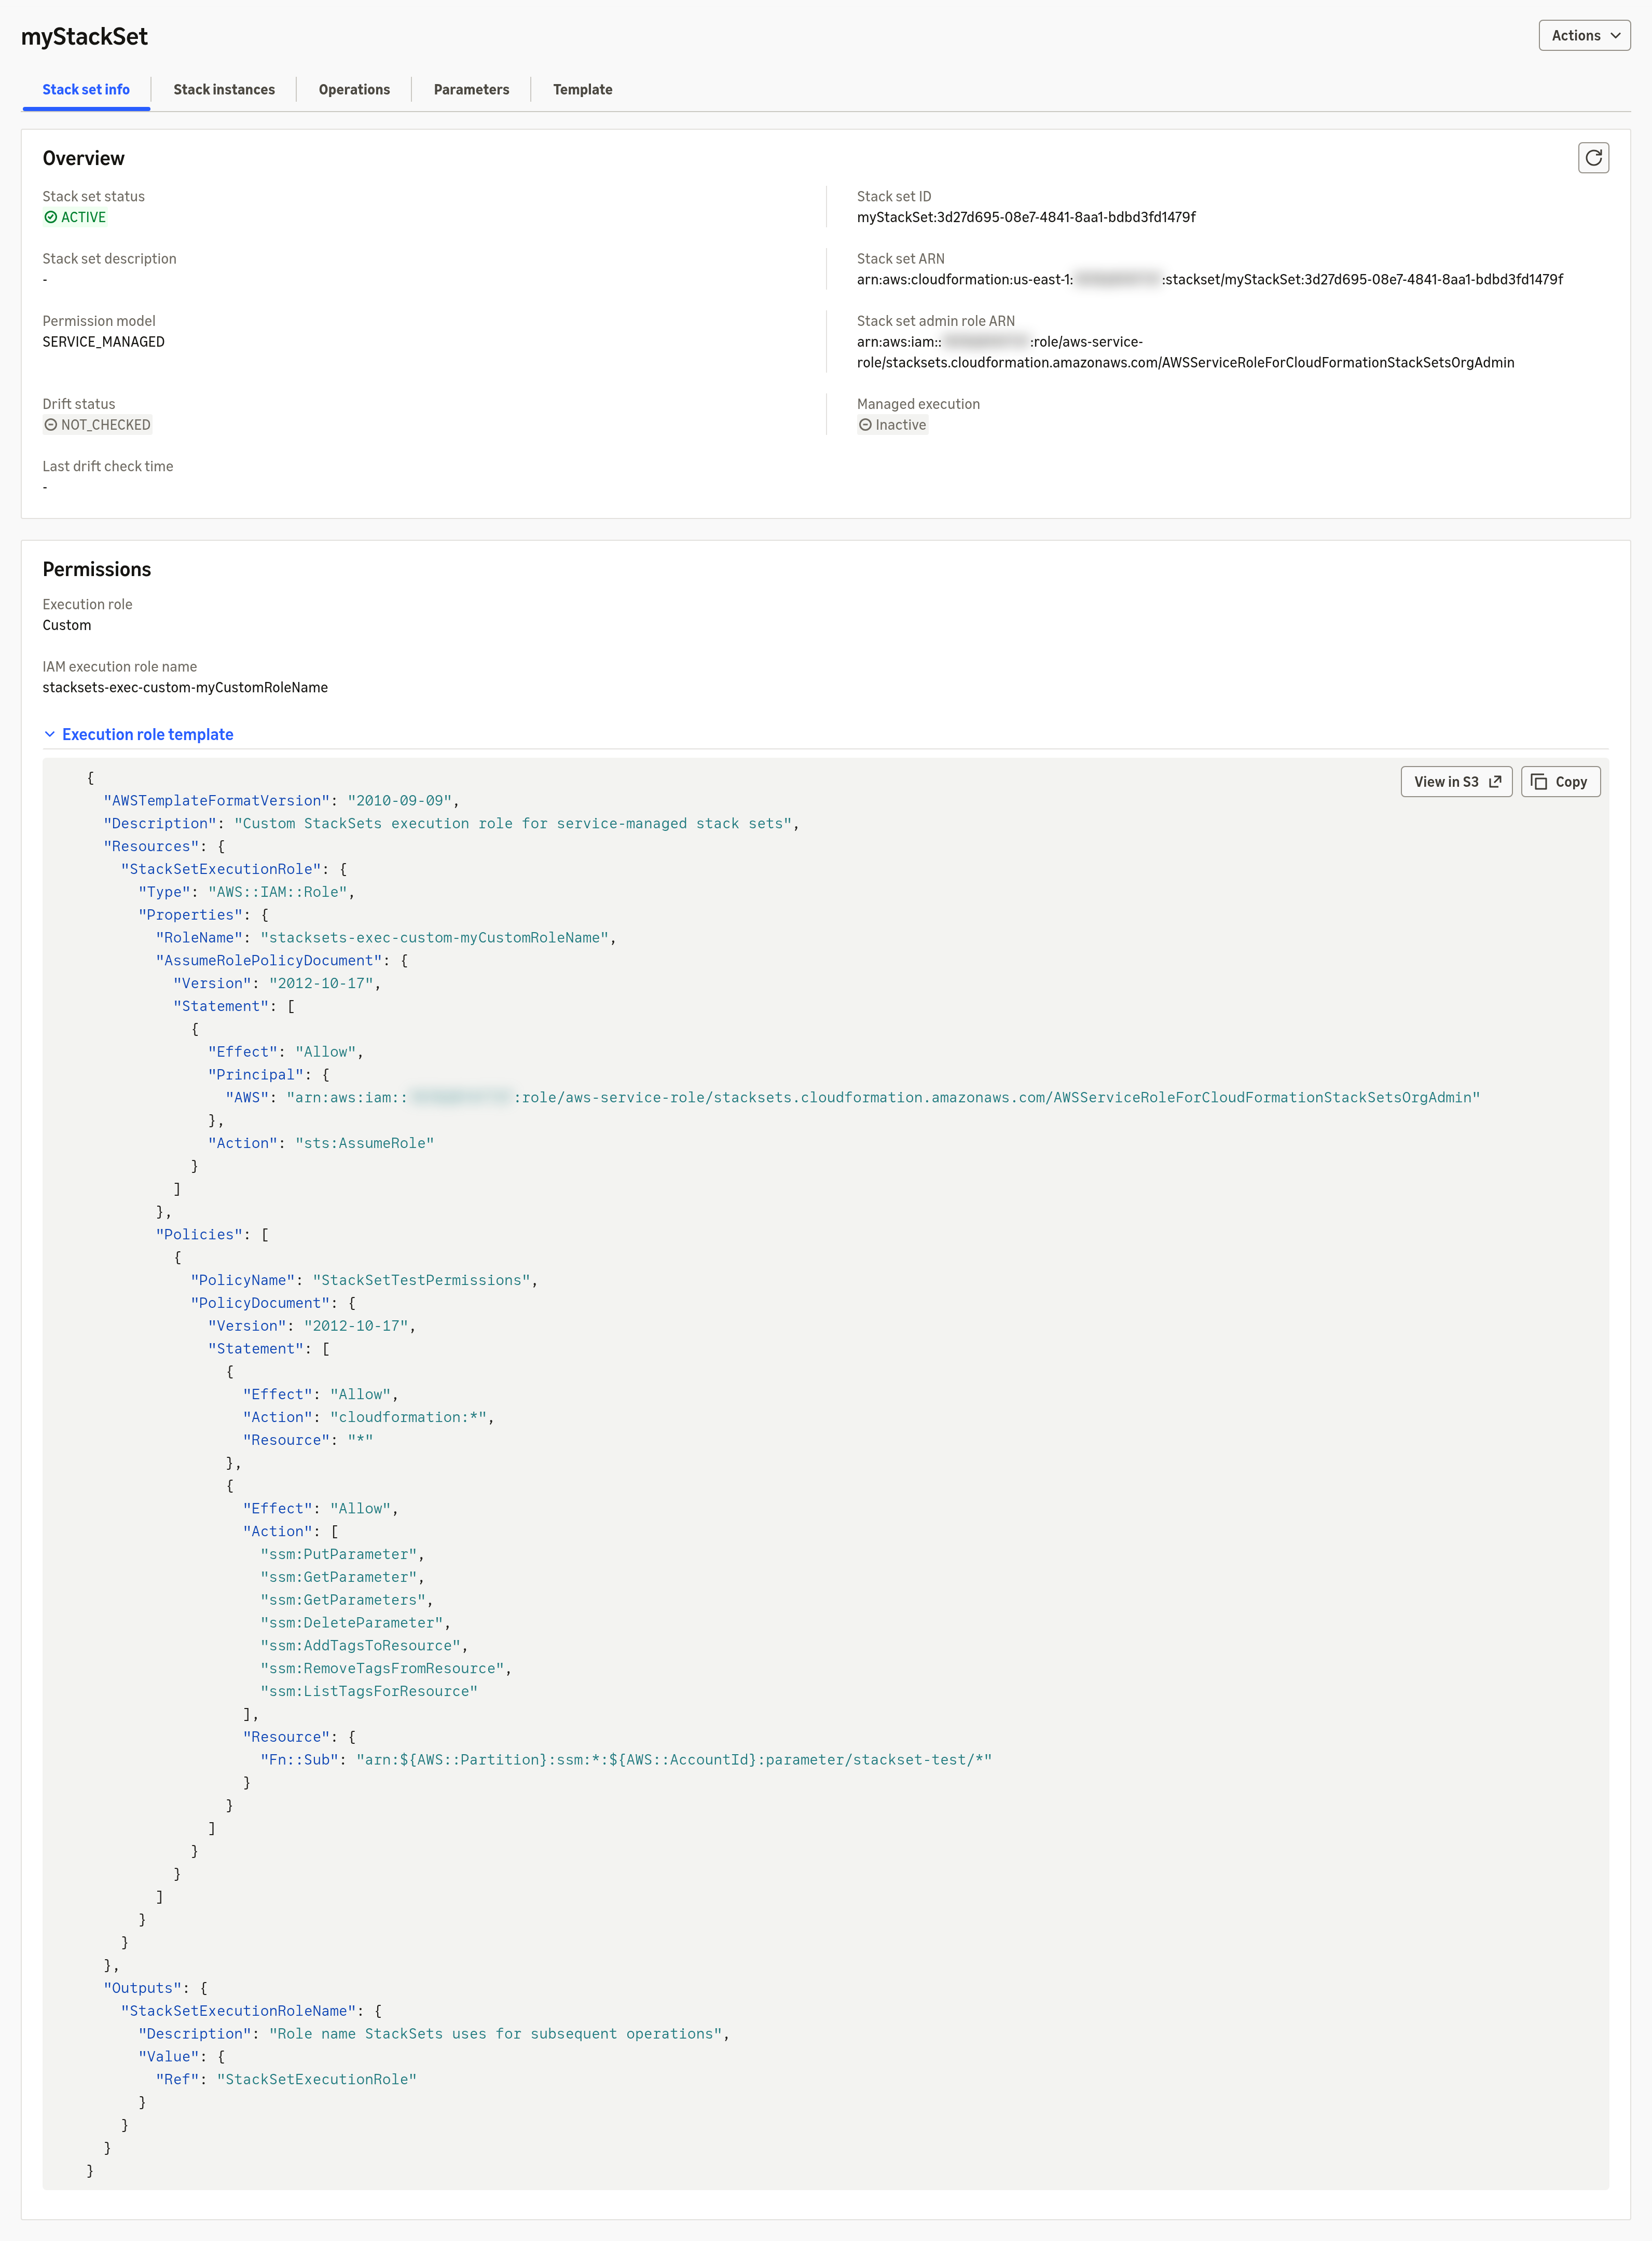
On the console, go to StackSet details, and under StackSet info expand Execution role template. The View in S3 button opens the stored template in a new tab. During update, the Use current execution role tile shows the template currently in use.

StackSet info tab on the console showing the configured execution role template with a View in S3 button, alongside the stack set ARN, admin role ARN, permission model, drift status, and stack set status.

Figure 6: The StackSet info tab showing the configured execution role template, where the View in S3 button opens the stored template in a new tab

If you configure a custom output bucket, StackSetOutputBucketPath in the DescribeStackSet response is configuration. It shows where StackSets writes the output file, not whether the write succeeded. Check S3 directly to confirm the object is present.

Common validation errors

CreateStackSet and UpdateStackSet validate your execution role template against the preceding requirements and return a ValidationException when something doesn’t match. Most error messages restate a requirement: more than one resource, a missing output key, a role name that doesn’t start with stacksets-exec-custom-, and so on. Three are easier to miss:

  • The account ID in the trust policy principal Amazon Resource Name (ARN) must be your organization’s management account, even when you’re using a delegated administrator.
  • The IAM role in the template must not set a Path property (other than /). This requirement isn’t obvious from the role’s shape.
  • When you update the execution role template, you can’t also specify deployment targets. StackSets always reprovisions the role in every existing stack instance.

For the full list of error strings and causes, see the Troubleshooting section of the User Guide.

If the execution role stack fails to create in a specific member account, that account’s stack instance deployment fails. Other accounts in the same deployment aren’t affected. Check the stack events in the failing member account for details, then retry by creating new stack instances for those accounts.

Get started

With custom execution role templates, you can keep the cross-account convenience of StackSets while bringing your permissions in line with least-privilege guidance. To learn more about the service, see the AWS CloudFormation product page.


About the authors

Tanvi Ravindra Malali

Tanvi Ravindra Malali

Tanvi Malali is a Delivery Consultant on the AWS Industries Healthcare team, where she helps healthcare customers design and deliver production workloads on AWS. She is a member of the AWS Technical Field Community for Infrastructure as Code. Tanvi is based in New York.

Idriss Laouali Abdou

Idriss Laouali Abdou

Idriss Abdou is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Track AWS CloudFormation StackSets deployments with progress visibility

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/track-aws-cloudformation-stacksets-deployments-with-progress-visibility/

Today, AWS CloudFormation StackSets adds deployment progress visibility, a stage-by-stage view of where each stack set operation stands. You can see how much work is complete, and which accounts and stack instances need attention. Whether you target tens of accounts or thousands, you can follow a deployment while it runs and act on results without waiting for it to finish.

With AWS CloudFormation, you model and provision your cloud infrastructure as code, writing templates in JSON or YAML or generating them with tools like the AWS Cloud Development Kit (CDK). CloudFormation StackSets extends this to many accounts and AWS Regions. With a stack set, you can deploy the same template, such as a networking baseline or security controls, to every account and Region you target in one operation. Each deployment of the template to one account and Region is a stack instance. With service-managed stack sets, StackSets works with AWS Organizations to provision the access it needs in each target account for you.

In this post, we’ll explore how to read deployment progress on the CloudFormation console and through the API. Whether you’re a platform engineer rolling out an organization-wide baseline or a developer building automation around StackSets, we’ll show you how to:

  • Follow a large deployment as it moves through each stage.
  • Find out why a deployment that reports success did not deploy any stacks.
  • Check progress from scripts and automation.
  • Review how each stage ended after the deployment completes.

The walkthrough shows how stage-level progress gives you confidence that a rollout is on track at every stage.

Key capabilities

Deployment progress adds the following to stack set operations that start after launch.

  • Two stages for every operation. Each stack set operation reports role provisioning and stack deployment separately, each with its own status and percentage complete.
  • Counts for each stage. Role provisioning reports accounts that succeeded, failed, completed, and are pending. Stack deployment reports stack instances that succeeded, failed, completed, are pending, were skipped, and were cancelled.
  • Progress for each Region. The console shows a Deployment by Region table, and describing an operation returns stack deployment progress for each Region.
  • Results after completion. Progress remains available after the operation finishes. You can review how each stage ended at any time.
  • Additive API change. The new fields are additive. Existing integrations continue to work without changes.

How it works

When you start a stack set operation, its overall status works as it does today. Deployment progress adds detail under StatusDetails.Stages in the DescribeStackSetOperation and ListStackSetOperations responses, and on the Progress tab of each operation on the CloudFormation console. The stage statuses are separate from the overall operation status.

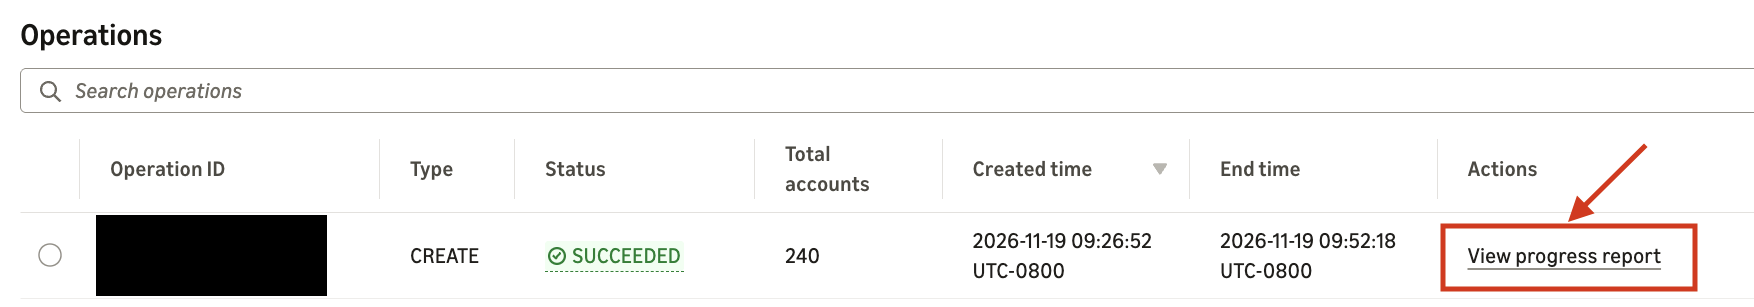
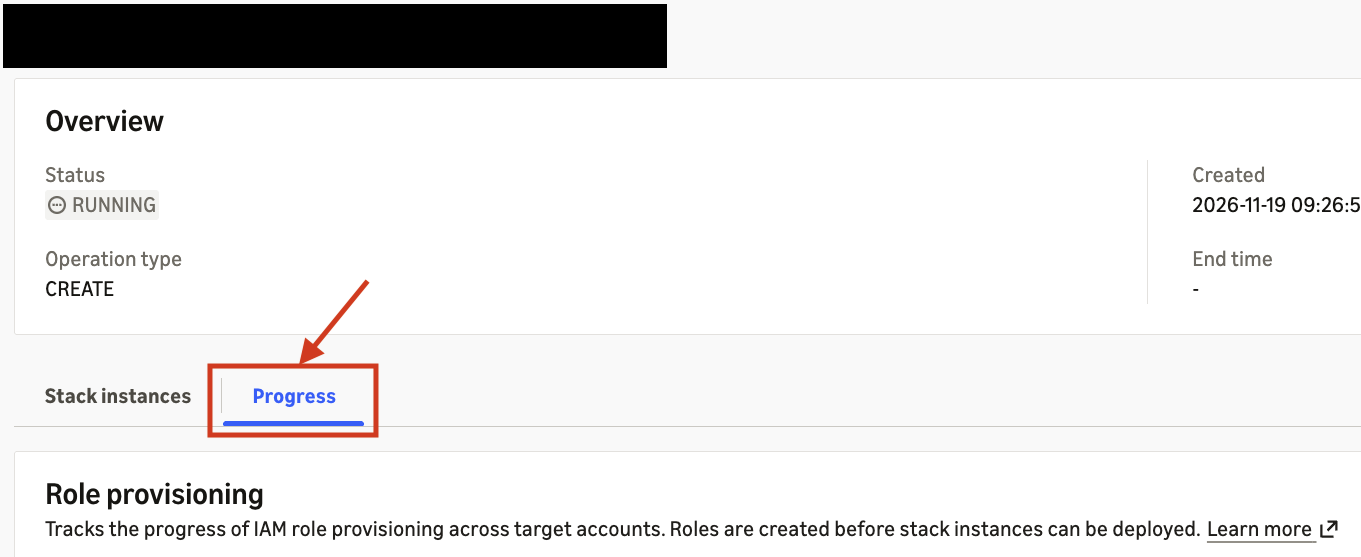
To open it on the console, choose View progress report for an operation on your stack set’s Operations tab. If the operation’s details page is already open, choose the Progress tab.

The following image shows the Operations tab for a stack set. The View progress report link for a completed CREATE operation is highlighted in the Actions column.

Operations tab with View progress report highlighted

Figure 1: Choose View progress report for an operation on the Operations tab

The following image shows the details page for the same operation while it was running, with the Progress tab highlighted next to the Stack instances tab.

Operation details page with the Progress tab highlighted

Figure 2: Alternatively, on an operation’s details page, choose the Progress tab

The Progress tab has up to three sections. Role provisioning shows the status and the succeeded, failed, pending, and total account counts. Deployment shows the status and the succeeded, failed, pending, cancelled, skipped, and total stack instance counts. Deployment by Region shows the same stack instance counts for each Region, and notes whether Regions are processed one at a time or in parallel. While an operation runs, a progress bar shows the Deployment percentage complete. When the operation finishes, the stage status replaces the progress bar. For operations on a self-managed stack set, the console leaves out the Role provisioning section and shows only Deployment and Deployment by Region. For other operations that don’t provision roles, such as updates, the Role provisioning section shows NOT_APPLICABLE. The completed count appears only in the API response, where it is the sum of succeeded, failed, skipped, and cancelled.

Role provisioning prepares access in each target account of a service-managed stack set. When StackSets has resolved the target accounts, the stage reports counts of succeeded, failed, completed, and pending accounts, and its percentage complete. In the API response, operations that don’t provision roles, including operations on self-managed stack sets, report this stage as NOT_APPLICABLE.

Stack deployment deploys your template as a stack instance in each account and Region. It begins after role provisioning finishes, and its counts appear once the stage starts. Two counts tell you why a stack instance was not deployed:

  • Skipped stack instances belong to accounts that did not complete role provisioning, or to suspended accounts. Because an operation has one stack instance per account in each Region, 4 accounts that did not complete role provisioning in a 3-Region operation give 12 skipped stack instances.
  • Cancelled stack instances were not attempted because the operation exceeded its failure tolerance or was stopped.

Completed is the sum of succeeded, failed, skipped, and cancelled, and pending is the total minus completed. The percentage complete is completed divided by total, rounded down to the nearest tenth. There is no separate in-progress count. StatusDetails also reports the total number of target accounts and stack instances once StackSets has resolved the operation’s targets.

Each stage reports one of these statuses: NOT_APPLICABLE, NOT_STARTED, IN_PROGRESS, SUCCEEDED, PARTIAL_SUCCESS, or FAILED. The two stages can end differently. For example, role provisioning can end in PARTIAL_SUCCESS while stack deployment ends in SUCCEEDED, because stack deployment succeeded for every stack instance that was not skipped.

Behavior by operation type

Operation Role provisioning Stack deployment
Create operations on a service-managed stack set, including auto-deployments Reported Reported
Update and delete operations on a service-managed stack set, and all operations on a self-managed stack set NOT_APPLICABLE Reported
Drift detection NOT_APPLICABLE NOT_APPLICABLE

This table reflects behavior at launch. To write automation that keeps working as StackSets adds features, read the role provisioning status in each response rather than inferring it from the operation type.

DescribeStackSetOperation includes stack deployment progress for each Region in RegionalStatusDetails. ListStackSetOperations returns the overall stages without the regional breakdown. Both stage progress and the Regional breakdown remain available after the operation finishes.

Scenario 1: Follow a large deployment as it runs

You’re a platform engineer rolling out a baseline from a service-managed stack set to 240 accounts in 3 Regions, which is 720 stack instances. The operation has been running for about 20 minutes and you want to know how far it has come.

On the console

  1. Open the CloudFormation console and choose StackSets.
  2. Choose your stack set, then choose the Operations tab.
  3. Choose View progress report for the running operation.

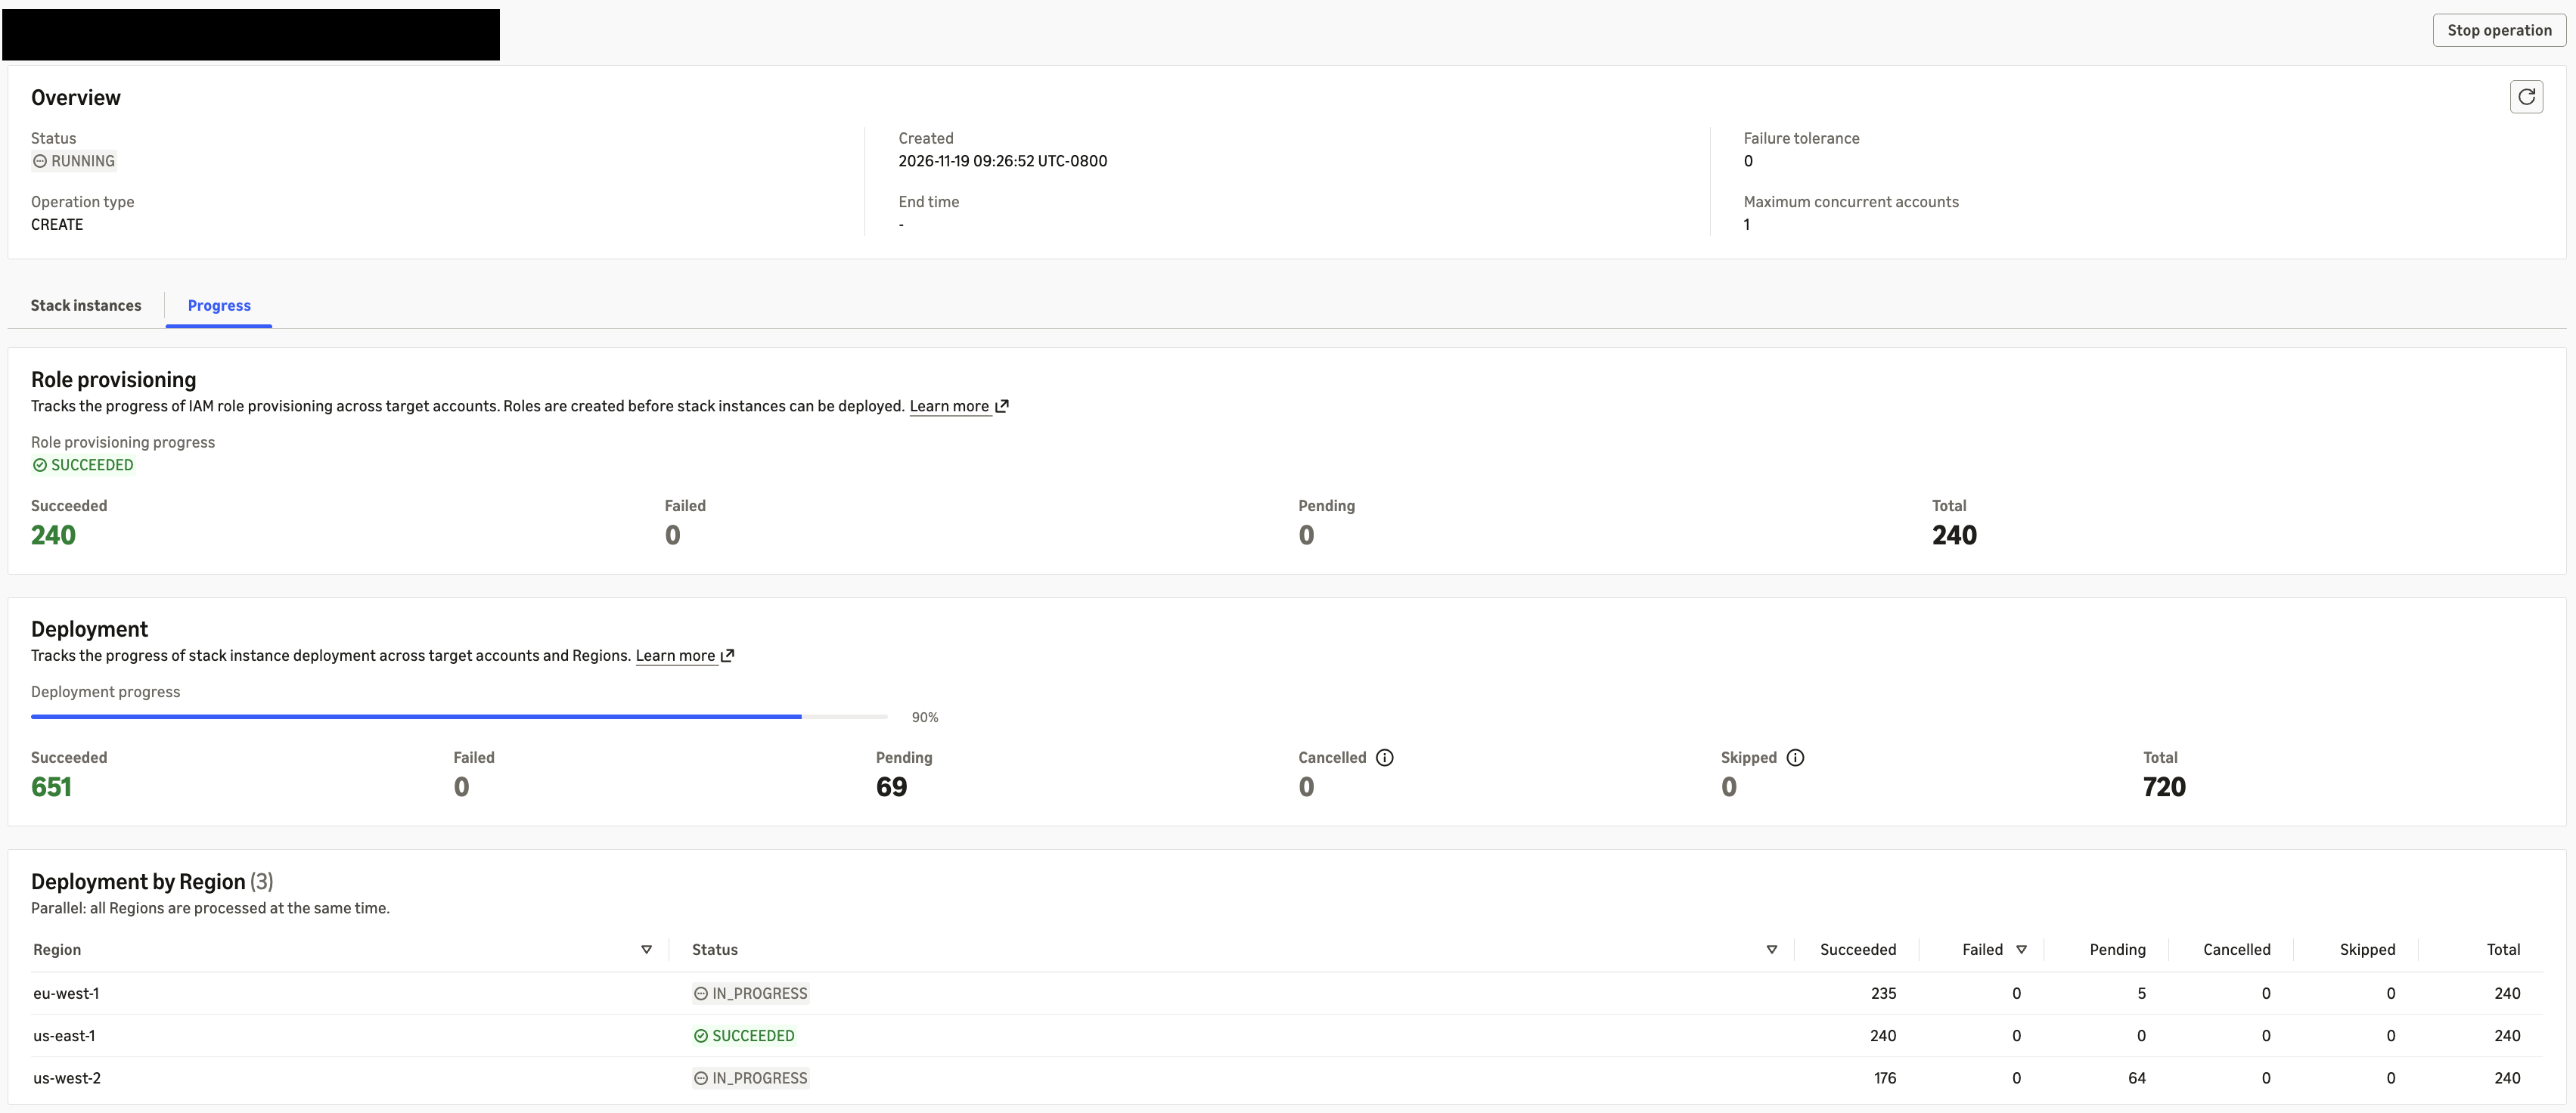
The following image shows the Progress tab for the operation while it runs, with the Deployment progress bar at 90 percent and progress for each Region.

Progress tab while a CREATE operation runs, with Deployment at 90 percent

Figure 3: Progress tab for a running operation

The overall status is still RUNNING, and the Progress tab shows what that status covers. Role provisioning has succeeded for all 240 accounts. The Deployment progress bar is at 90 percent, with 651 stack instances succeeded, none failed, and 69 pending. Deployment by Region shows the status for each Region. The US East (N. Virginia) Region (us-east-1) is done, the Europe (Ireland) Region (eu-west-1) has 5 stack instances pending, and the US West (Oregon) Region (us-west-2) has 64 pending. You can let the operation continue with confidence that it is progressing.

With the AWS Command Line Interface

aws cloudformation describe-stack-set-operation \
    --stack-set-name demo-operation-progress-visibility \
    --operation-id 01234567-890a-bcde-f012-34567890abcd

Sample output (abbreviated):

{
  "StackSetOperation": {          
    "OperationId": "01234567-890a-bcde-f012-34567890abcd",
    "Action": "CREATE",
    "Status": "RUNNING",
    "StatusDetails": {
      "Stages": {
        "RoleProvisioning": {
          "Status": "SUCCEEDED",
          "SucceededAccountsCount": 240,
          "FailedAccountsCount": 0,
          "PendingAccountsCount": 0,
          "CompletedAccountsCount": 240,
          "PercentageCompleted": 100
        },
        "StackInstancesDeployment": {
          "Status": "IN_PROGRESS",
          "SucceededStackInstancesCount": 651,
          "FailedStackInstancesCount": 0,
          "PendingStackInstancesCount": 69,
          "CompletedStackInstancesCount": 651,
          "SkippedStackInstancesCount": 0,
          "CancelledStackInstancesCount": 0,
          "PercentageCompleted": 90.4
        }
      },
      "TotalAccountsCount": 240,
      "TotalStackInstancesCount": 720,
      "FailedStackInstancesCount": 0
    },
    "RegionalStatusDetails": {
      "eu-west-1": {
        "Stages": {
          "RegionalStackInstancesDeployment": {
            "Status": "IN_PROGRESS",
            "SucceededStackInstancesCount": 235,
            "FailedStackInstancesCount": 0,
            "PendingStackInstancesCount": 5,
            "CompletedStackInstancesCount": 235,
            "SkippedStackInstancesCount": 0,
            "CancelledStackInstancesCount": 0,
            "TotalStackInstancesCount": 240,
            "PercentageCompleted": 97.9
          }
        }
      },
      "us-east-1": { ... "Status": "SUCCEEDED", "PercentageCompleted": 100 ... },
      "us-west-2": {
        "Stages": {
          "RegionalStackInstancesDeployment": {
            "Status": "IN_PROGRESS",
            "SucceededStackInstancesCount": 176,
            "FailedStackInstancesCount": 0,
            "PendingStackInstancesCount": 64,
            "CompletedStackInstancesCount": 176,
            "SkippedStackInstancesCount": 0,
            "CancelledStackInstancesCount": 0,
            "TotalStackInstancesCount": 240,
            "PercentageCompleted": 73.3
          }
        }
      }
    }
  }
}

The API reports the percentage rounded down to the nearest tenth (651 of 720 is 90.4 percent). The console progress bar shows 90%.

Scenario 2: Find out why nothing deployed

You start a create operation that targets 4 accounts in 3 Regions, which is 12 stack instances. The operation finishes in seconds with an overall status of SUCCEEDED, but no stacks appear in the target accounts.

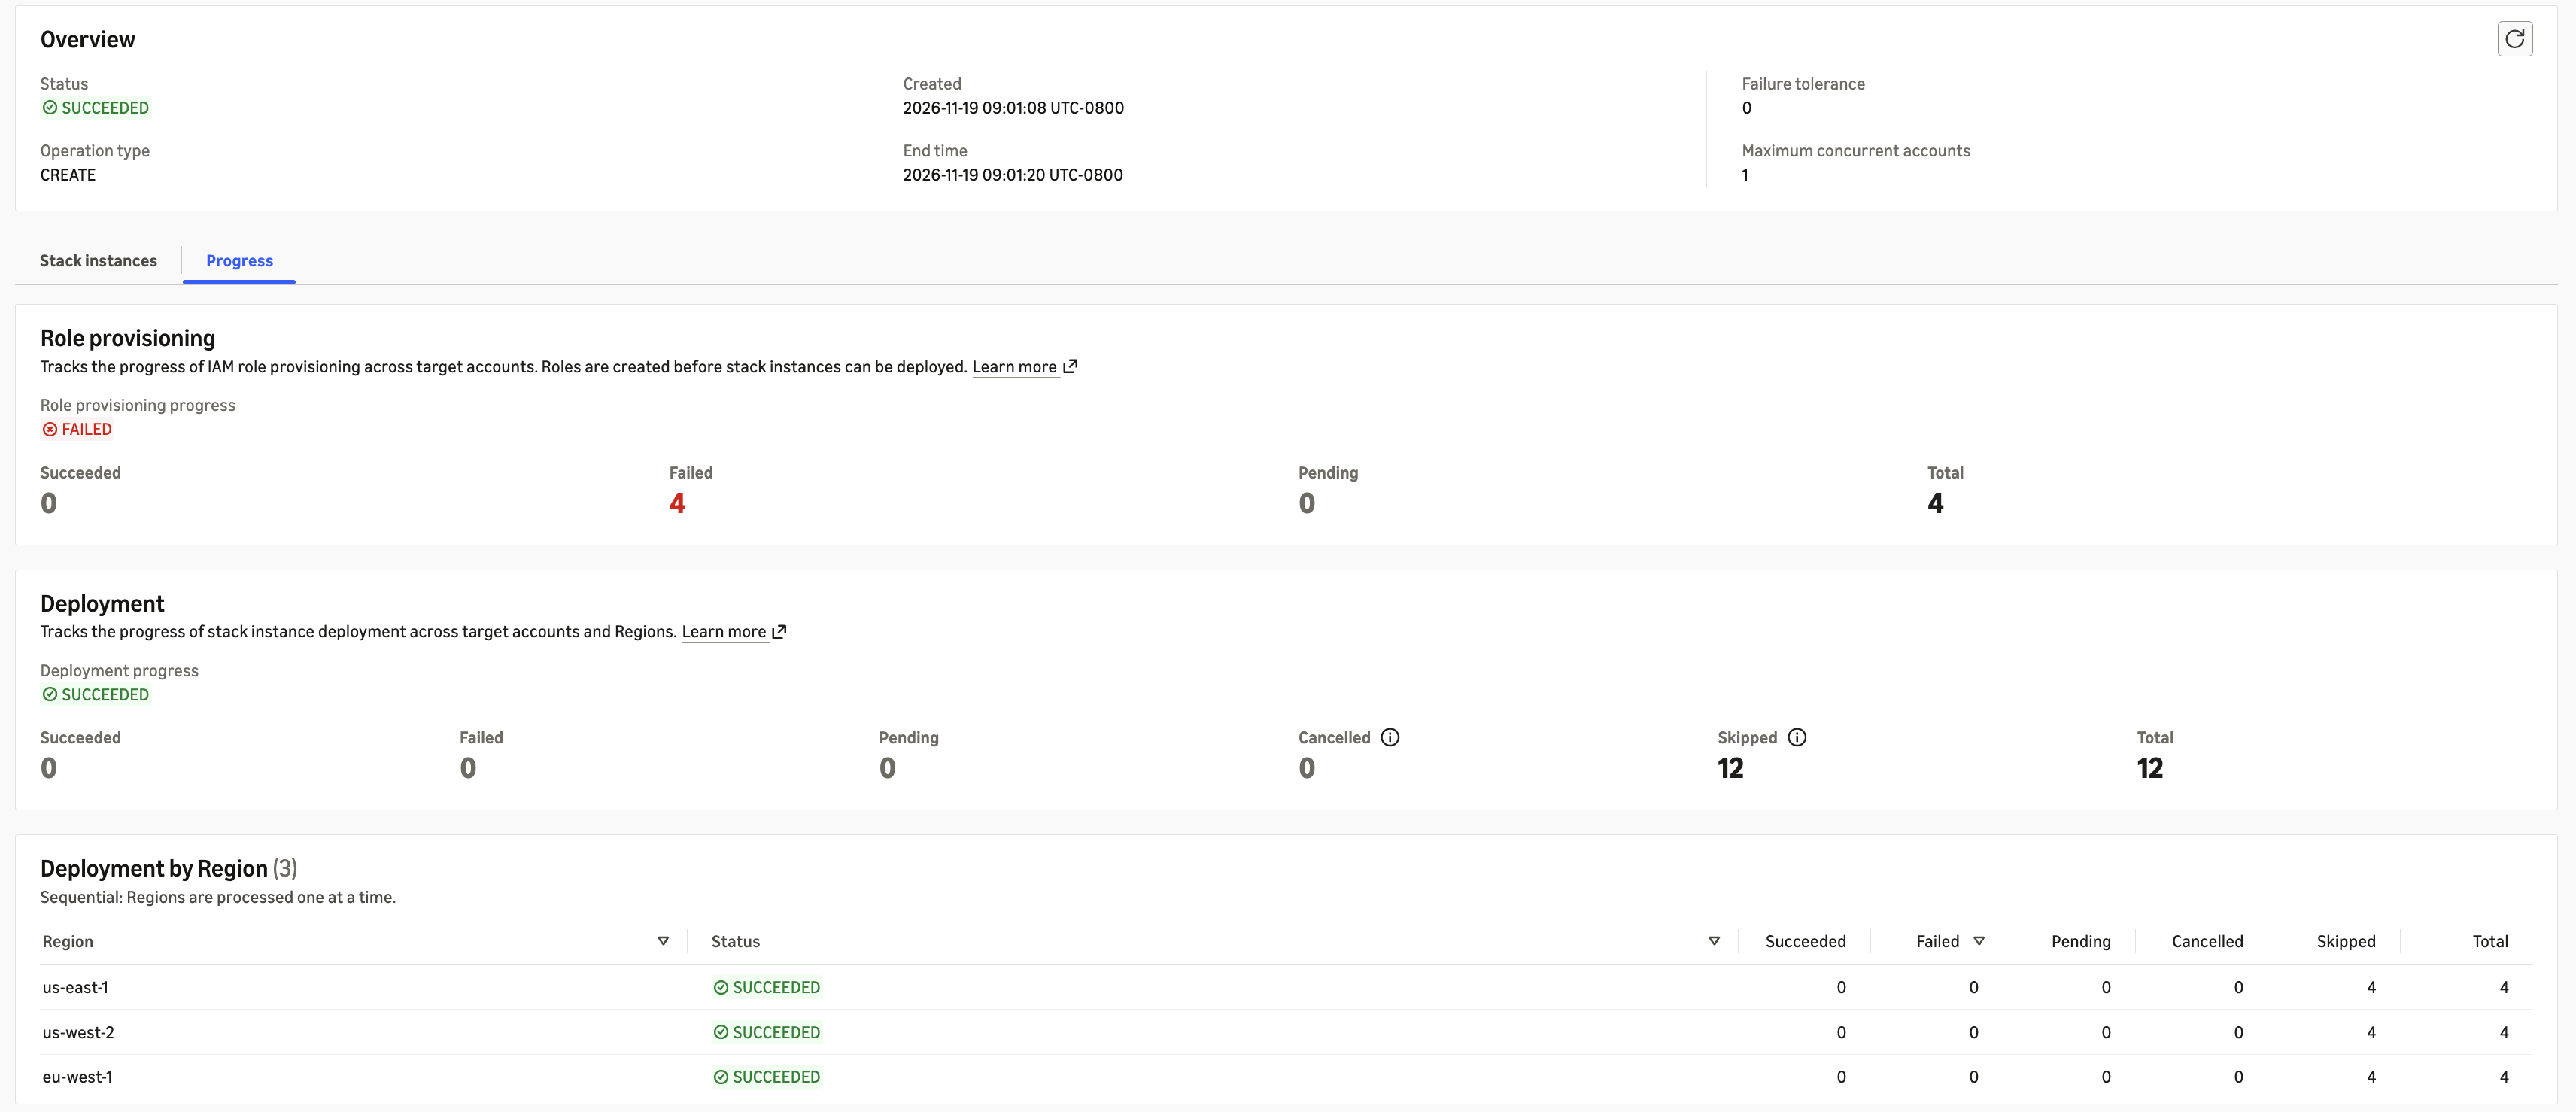
The following image shows the Progress tab after the operation finished. Role provisioning shows FAILED for all four accounts, and Deployment shows SUCCEEDED with all 12 stack instances skipped.

Progress tab after role provisioning failed in all four accounts

Figure 4: Progress tab after role provisioning failed in every target account

The Progress tab shows what happened. Role provisioning is FAILED, with all 4 accounts failed. Deployment is SUCCEEDED because no stack instance failed, but all 12 stack instances are skipped. Deployment by Region shows 4 skipped stack instances in each Region. Role provisioning did not complete in any account, so StackSets had nothing to deploy. In this example, all four target accounts were suspended.

Sample output (abbreviated):

"StatusDetails": {
  "Stages": {
    "RoleProvisioning": {
      "Status": "FAILED",
      "SucceededAccountsCount": 0,
      "FailedAccountsCount": 4,
      "PendingAccountsCount": 0,
      "CompletedAccountsCount": 4,
      "PercentageCompleted": 100
    },
    "StackInstancesDeployment": {
      "Status": "SUCCEEDED",
      "SucceededStackInstancesCount": 0,
      "FailedStackInstancesCount": 0,
      "PendingStackInstancesCount": 0,
      "CompletedStackInstancesCount": 12,
      "SkippedStackInstancesCount": 12,
      "CancelledStackInstancesCount": 0,
      "PercentageCompleted": 100
    }
  },
  "TotalAccountsCount": 4,
  "TotalStackInstancesCount": 12,
  "FailedStackInstancesCount": 0
}

To see the status reason for each account, list the operation’s results:

aws cloudformation list-stack-set-operation-results \
    --stack-set-name demo-operation-progress-visibility \
    --operation-id <operation-id> \
    --query "Summaries[?Status=='FAILED'].{Account:Account,Region:Region,Reason:StatusReason}"

Your next step is to review the affected accounts, for example confirming whether they are active in AWS Organizations, and then run the operation again for them.

Scenario 3: Check progress from scripts and automation

You run StackSets operations from a pipeline and want a short progress line in your build logs. ListStackSetOperations returns the same stage details for recent operations, without the Regional breakdown:

aws cloudformation list-stack-set-operations \
    --stack-set-name demo-operation-progress-visibility \
    --query "Summaries[?Status=='RUNNING'].{Id:OperationId,Stages:StatusDetails.Stages}"

For one operation, you can extract the stack deployment percentage directly:

aws cloudformation describe-stack-set-operation \
    --stack-set-name demo-operation-progress-visibility \
    --operation-id 01234567-890a-bcde-f012-34567890abcd \
    --query "StackSetOperation.StatusDetails.Stages.StackInstancesDeployment.PercentageCompleted"

Sample output, for the operation in Scenario 1:

90.4

For operations that start after launch, every stage is present in the response, with NOT_APPLICABLE or NOT_STARTED when it is not active. Your automation reads the same structure for every operation type. AI agents that call the CloudFormation API on your behalf can read the stage status to tell whether a stage is active. Operations that ran before launch don’t include Stages in their response, so check that the field exists before you read it, for example when you list older operations.

Scenario 4: Review how each stage ended

The operation from Scenario 1 has finished. You want to confirm the result before you move on.

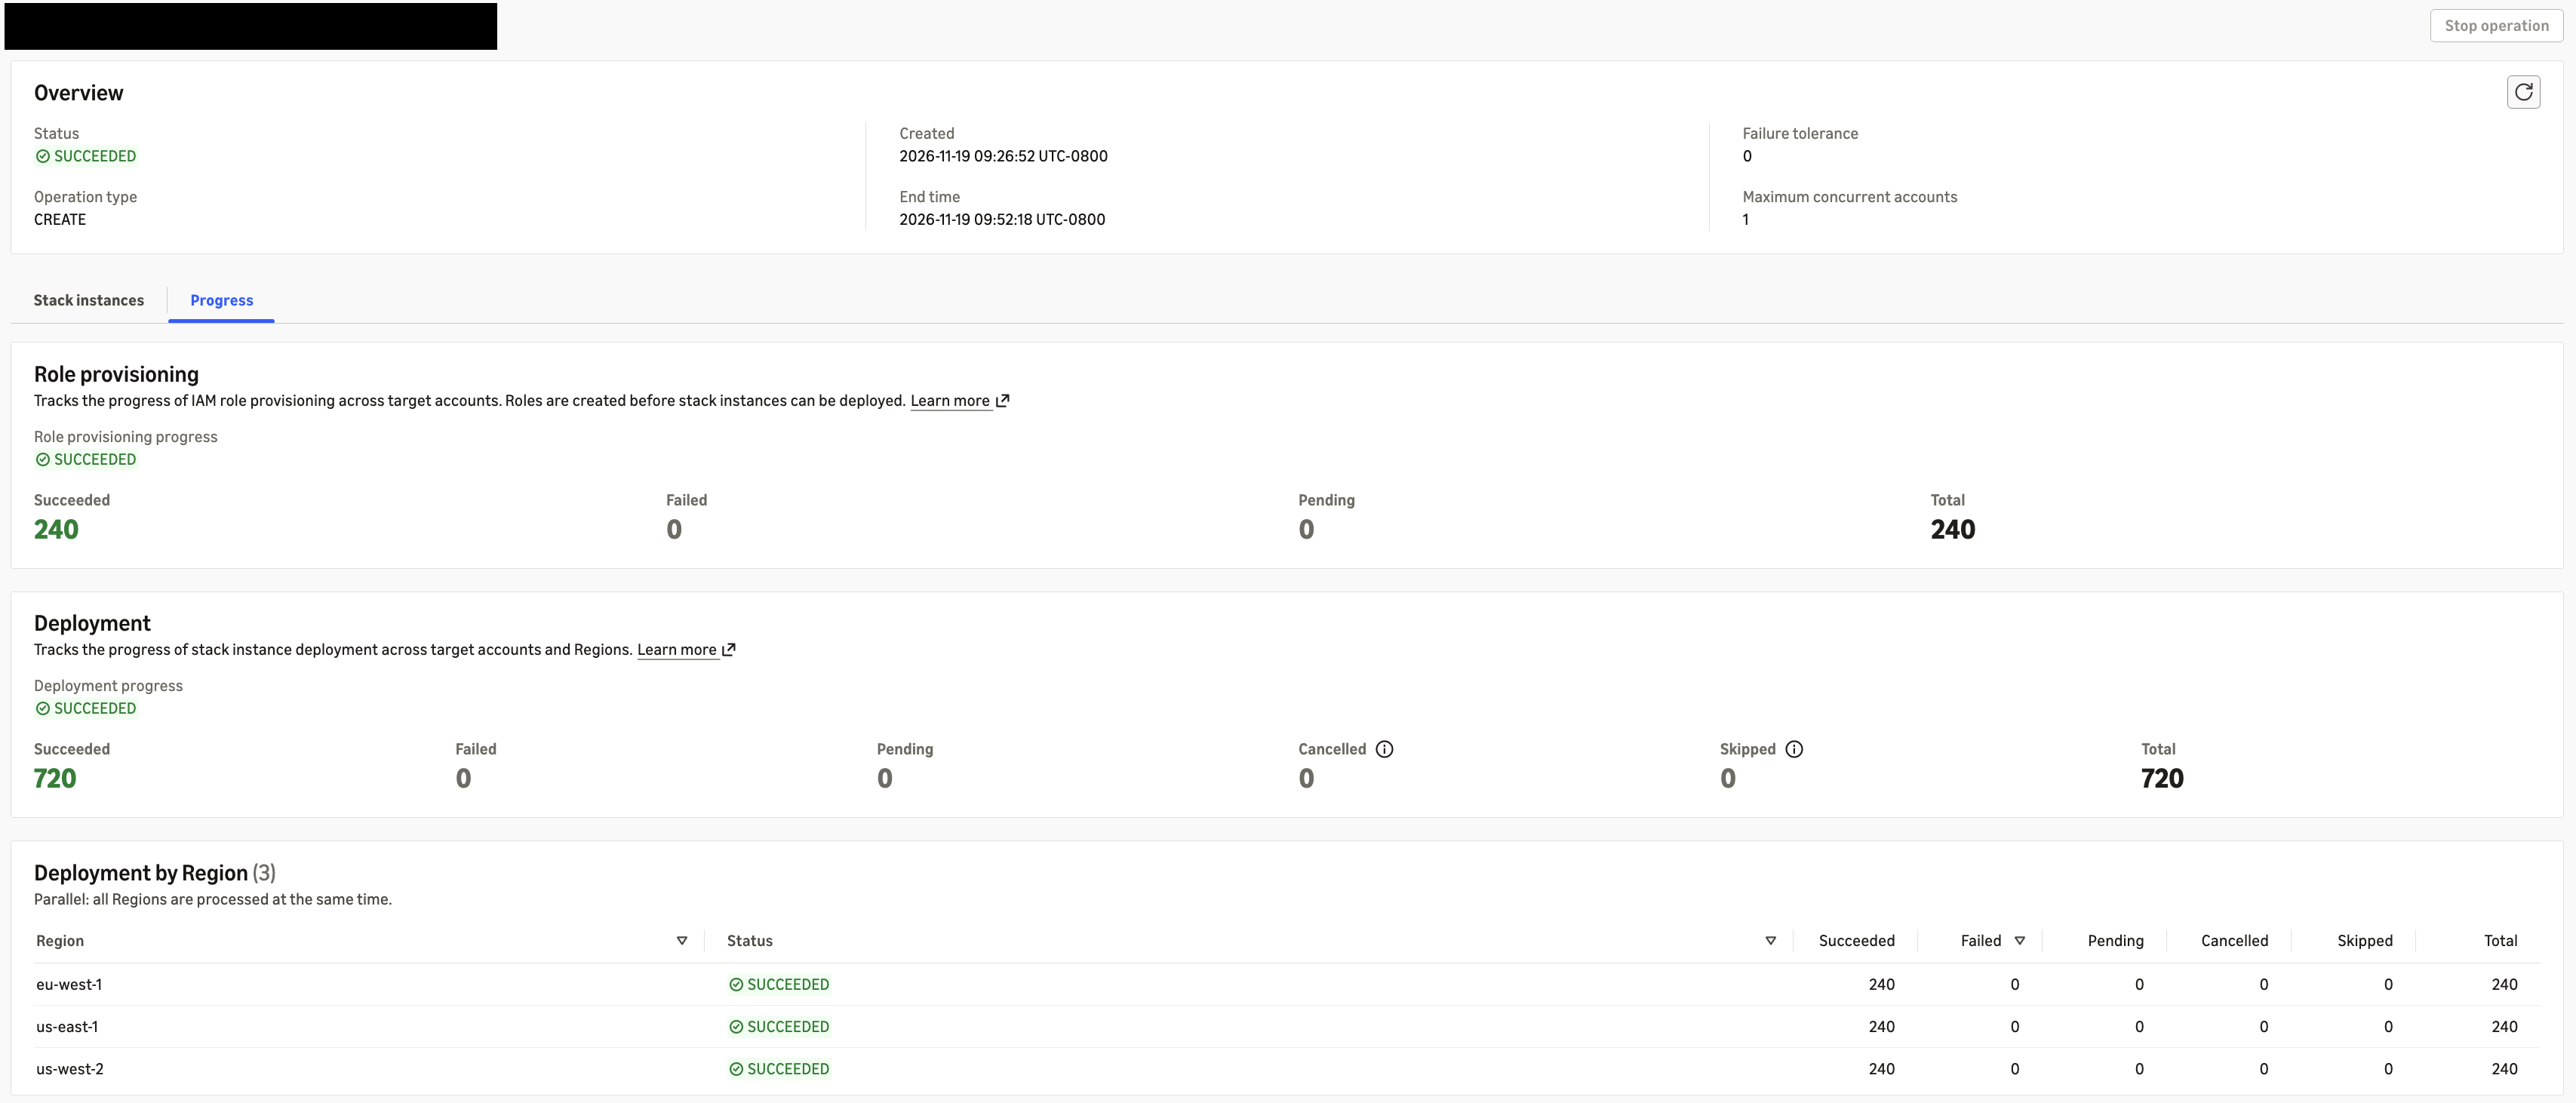
The following image shows the Progress tab after the operation completed, with both stages and all three Regions showing SUCCEEDED.

Progress tab after the operation completed

Figure 5: Progress tab for the completed operation

The overall status is SUCCEEDED. Role provisioning succeeded for all 240 accounts. Deployment shows SUCCEEDED in place of the progress bar, with all 720 stack instances succeeded and none failed, pending, cancelled, or skipped. Deployment by Region shows 240 succeeded stack instances in each of the 3 Regions. Because progress remains available after the operation finishes, you can come back to these results later.

Best practices

  • Use the counts to decide your next step. Failed stack instances point to the template or the resources it creates. Skipped stack instances point to role provisioning, or a suspended account. Cancelled stack instances point to the failure tolerance, or a stopped operation.
  • Check role provisioning and the overall status. If role provisioning fails for every target account, StackSets skips every stack instance. As Scenario 2 shows, stack deployment and the overall operation still report SUCCEEDED, even though no stacks were deployed. A FAILED role provisioning status with a skipped count equal to the total tells you this happened.
  • Use DescribeStackSetOperation when you need the Regional breakdown, and ListStackSetOperations for a quick view across recent operations.
  • Treat NOT_APPLICABLE in the API response as expected for the operation type, for example role provisioning on self-managed stack sets or both stages for drift detection.
  • Totals and pending counts appear only after StackSets resolves the operation’s targets. Handle their absence early in an operation, and for operations that ran before launch, which don’t include Stages.

Getting started

Deployment progress is available at no additional charge in all AWS Regions where CloudFormation StackSets is supported. On the CloudFormation console, choose View progress report for a stack set operation on the Operations tab. You can also call DescribeStackSetOperation or ListStackSetOperations with the AWS Command Line Interface (AWS CLI) or AWS SDKs. To use the new fields from the command line, use AWS CLI version 2. They are not available in AWS CLI version 1. In code, use an AWS SDK version released on or after November 18, 2026.

Conclusion

Deployment progress shows where each StackSets deployment stands, stage by stage and Region by Region. You can follow a rollout across thousands of accounts, find the accounts and stack instances that need attention while it runs, and review how each stage ended afterward. Existing integrations continue to work without changes.

For a full description of each stage, status, and count, including how they differ by operation type, see Monitor StackSet operation progress in the AWS CloudFormation User Guide. If you’re building automation, the DescribeStackSetOperation and ListStackSetOperations pages in the AWS CloudFormation API Reference list every new response field. To learn more about modeling and provisioning infrastructure as code across accounts and Regions, visit the AWS CloudFormation product page.


About the authors

Idriss Laouali Abdou

Idriss Laouali Abdou

Idriss is a Senior Product Manager at AWS, working on delivering the best experience for AWS IaC customers. Outside of work, you can either find him creating educational content helping thousands of students, cooking, or dancing.

Nitin Patil

Nitin Patil

Nitin is a Software Development Engineer at AWS who has worked in the AWS IaC space for the past five years, mostly on CloudFormation StackSets. Outside of work, you can find him exploring new cafes, playing badminton, or gathered around a board game.

How Klaviyo processes 3 billion daily events at scale with Amazon MSK Express

Post Syndicated from Jonathan Li original https://aws.amazon.com/blogs/big-data/how-klaviyo-processes-3-billion-daily-events-at-scale-with-amazon-msk-express/

Klaviyo (NYSE: KVYO) is an autonomous business-to-consumer (B2C) customer relationship management (CRM) platform used by more than 200,000 brands to understand and act on customer relationships in real time. Every personalized email, SMS, and push notification that Klaviyo sends depends on a streaming pipeline that ingests roughly 3 billion events per day. These events range from email opens and website visits to purchase completions and cart abandonments.

In this post, we share how Klaviyo migrated from RabbitMQ to Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers. We also show how Amazon MSK Express let a small team scale its event pipeline ahead of Black Friday/Cyber Monday (BFCM) 2025. With Amazon MSK Express, Klaviyo delivered more than 22.7 billion messages, up 25 percent year over year, and scaled back down afterward over a five-day period.

The challenge

Events are the lifeblood of Klaviyo’s platform. Every customer interaction flows through the streaming pipeline. Klaviyo’s previous RabbitMQ-based event infrastructure supported the platform through years of rapid growth. As volume climbed, scaling it beyond a certain point became increasingly difficult, so the team set out to build a foundation for the next stage of scale, with three requirements:

  • Absorb extreme bursts – BFCM drives roughly 7 times normal event volume, concentrated into five days.
  • Serve two service level objective (SLO) classes on one pipeline – Real-time triggers (5-second SLO) and analytics aggregates (20-minute SLO) share infrastructure, so slower work can never hold up time-critical events.
  • Zero data loss – Every event is a customer interaction that drives personalized marketing, so nothing can be silently dropped.

The replacement had to sustain peaks of 170,000 events per second, absorb a 7 times spike, and scale back down afterward.

Solution overview

Klaviyo rebuilt its event gateway infrastructure on Apache Kafka, choosing Amazon MSK Express brokers as its fully managed streaming backbone serving as the front door for all inbound events.

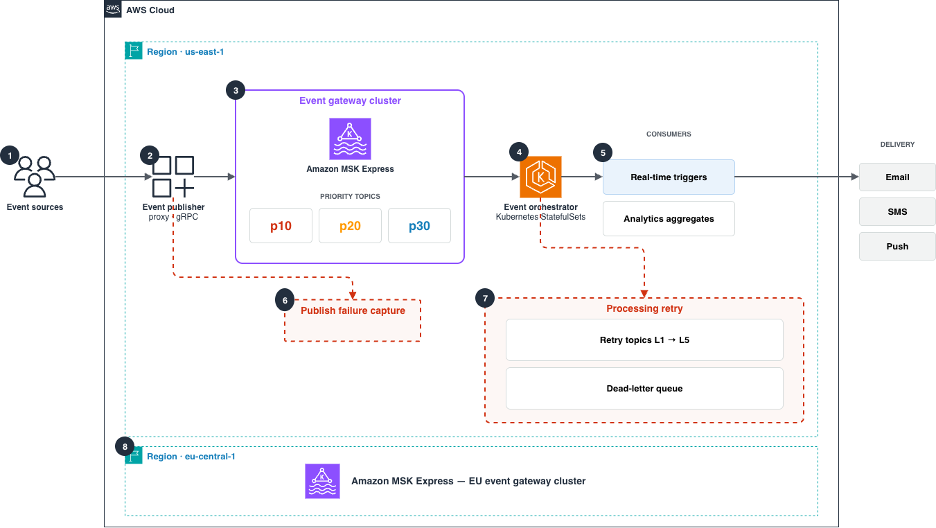
Klaviyo event pipeline on Amazon MSK Express, from event sources through the event gateway and orchestrator to consumers and delivery channels

Figure 1: Klaviyo’s event gateway architecture on Amazon MSK Express, showing the gRPC publisher, p10/p20/p30 priority topics, the Kubernetes orchestrator, retry topics and dead-letter queue, Amazon S3 failure capture, and a second gateway cluster in eu-central-1

The solution includes the following key components:

  • Event gateway cluster – The entry point for all inbound events (email opens, clicks, site activity, API calls), running on express.m7g.4xlarge brokers in the US, with a second cluster in the EU.
  • Three-tier priority topics – Events are routed to priority topics (p10, p20, p30) with 360 partitions each. The partition count is set by the consumer topology rather than the broker count: the event orchestrator runs as StatefulSets with one pod per partition, which comes to 90 pods in each of four Kubernetes clusters and 360 pods in total.
  • Graduated retry architecture – Five retry delay levels with exponential backoff, plus a dead-letter queue, so no event is silently dropped.

Priority-based event processing

Rather than treating all events equally, Klaviyo routes events to priority tiers through a gRPC publisher proxy. This design degrades gracefully under extreme load. High-priority events (such as purchase confirmations that trigger transactional flows) are processed first, while lower-priority events (such as batch analytics updates) can tolerate higher latency.

Critically, Klaviyo runs one unified set of processors across all three priority levels instead of standing up separate infrastructure per level. That consolidation cut costs by roughly 30 percent through improved resource utilization. For the design in depth, see Building a Distributed Priority Queue in Kafka.

Resilient event publishing

Klaviyo designed its event publisher to survive failure at every layer. A publish that fails against one Kafka cluster has several fallback mechanisms to make sure that there will be no permanent data loss. Most failures recover automatically, and the rest are preserved for replay. Over one three-month window, roughly 20,000 events were recovered without human intervention, out of approximately 300 billion processed in that period.

Klaviyo also retains seven days of event history for replay in the case of downstream incidents.

For more on Klaviyo’s eventing design, see Rebuilding Event Infrastructure at Scale and Building a Resilient Event Publisher with Dual Failure Capture.

Scaling for Black Friday with MSK Express

The clearest demonstration of this architecture came during BFCM 2025, the largest ecommerce event of the year, when the pipeline carried the traffic behind Klaviyo customers’ most revenue-critical campaigns across five consecutive days.

The scale-out timeline

Period Brokers Context
Steady state (through September 2025) 12 Normal daily processing of ~3B events
Early October 2025 18 First capacity increase ahead of the holiday season
Late October–November 2025 (BFCM) 60 Full Black Friday / Cyber Monday capacity
December 2025 (post-BFCM) 18 Optimized steady-state fleet

The team scaled the event gateway cluster up several-fold over about seven weeks, held it through Cyber Monday, then scaled it back down in December.

Why MSK Express made this possible

Three capabilities of MSK Express were critical to making this operational with a lean team.

No storage provisioning – Express brokers remove storage sizing and provisioning entirely. You pay for the data ingested into the cluster and the data stored in it, per GB per hour, and all stored data is replicated across three Availability Zones for high availability. This pay-as-you-go model eliminates wasted capacity costs. For Klaviyo, it meant a large holiday scale-out required no storage capacity planning at all.

Intelligent Rebalancing – Adding brokers to an Apache Kafka cluster normally means redistributing partition data across the new brokers, which traditionally requires careful manual planning, monitoring, and throttle management. MSK Express Intelligent Rebalancing automates that redistribution without manual intervention or performance degradation, and AWS reports that Express brokers rebalance partitions 180 times faster than Standard brokers. For Klaviyo, this meant adding brokers at scale for BFCM without an engineer owning partition reassignment at scale.

Built-in high availability – Based on AWS internal testing, Express brokers recover from failure 90 percent faster than Standard brokers, thanks to storage improvements. A replacement node starts up with almost no disruption to the rest of the cluster, rather than triggering a significant rebalance. Express brokers are also highly available by default, with the service managing the critical cluster and topic configurations that would otherwise need hand-tuning.

Results

Since migrating to Amazon MSK Express, Klaviyo has achieved the following results:

  • Multi-fold broker scale-out in under two months to absorb BFCM peak traffic, with a clean scale-down afterward.
  • Approximately 30 percent cost reduction from running unified processors across all three priority levels instead of separate infrastructure per level.
  • 5-second SLO held for real-time event triggers at a peak of 170,000 events per second.
  • 22.7 billion messages delivered over BFCM 2025, up 25 percent year over year.
  • Multi-Region since May 2026, with a second event gateway cluster in eu-central-1 serving European customers.
  • MSK Express adopted across Klaviyo’s event gateway clusters in both US and EU AWS Regions.

As Klaviyo’s engineering team wrote in Rebuilding Event Infrastructure at Scale:

“Moving to managed Kafka infrastructure on AWS MSK was one of those decisions that keeps paying dividends.”

It freed up engineers to spend their time building features rather than operating messaging infrastructure.

Key learnings

Based on Klaviyo’s experience building and operating this architecture, here are key takeaways for teams considering a similar approach:

  • Design for extreme elasticity from day one – Klaviyo’s BFCM traffic drives a multi-fold surge in event volume into five days. Designing partition layouts, topic structures, and consumer groups to accommodate elastic scaling before you need it avoids painful re-architecture under pressure.
  • Size partitions for your consumers, not your brokers – Klaviyo’s 360 partitions per topic come from its consumer topology (one orchestrator pod per partition), which stays fixed while the broker fleet scales up and back down underneath it. Coupling partition count to broker count would have forced a partition change in the middle of the holiday ramp.
  • Scale down as deliberately as you scale up – Klaviyo returned to a right-sized fleet after BFCM rather than carrying peak capacity all year. Because Express bills storage per GB rather than per provisioned volume, scaling down left no stranded storage cost behind.
  • Run multiple SLO classes on one pipeline – A single set of processors serves all three priority tiers, which cut costs by roughly 30 percent. Priority routing still protects latency: real-time triggers held their 5-second SLO at a peak of 170,000 events per second.
  • Build fault tolerance into every layer – Cross-cluster failover, a dead-letter queue, and an Amazon Simple Storage Service (Amazon S3) fallback mean individual failures don’t cause data loss. Express broker recovery keeps a lost broker from turning into a cluster-wide disruption.

Conclusion

Klaviyo’s journey from RabbitMQ to Amazon MSK Express demonstrates how a managed streaming service helps high-growth companies operate mission-critical event infrastructure at massive scale without proportionally growing their operations team. By combining MSK Express Intelligent Rebalancing with thoughtful architecture design (priority-based topics, graduated retry queues, and layered failure capture), Klaviyo’s lean infrastructure team scaled 5 times during the largest ecommerce event of the year.

Klaviyo’s use of Amazon MSK has since grown beyond the event pipeline. Its change data capture (CDC) infrastructure now runs on Amazon MSK Express as well. The team is also evaluating migrating its remaining self-managed Apache Kafka clusters on Amazon Elastic Compute Cloud (Amazon EC2), which serve data lake workloads, to MSK.

If you’re operating Apache Kafka workloads that require elastic scaling, operational simplicity, or both, consider Amazon MSK Express brokers for your next streaming workload.


About the authors

Jonathan Li

Jonathan Li

Jonathan is a Lead Engineer at Klaviyo, where his Data Automation team owns most of the company’s Apache Kafka infrastructure and tooling, including its change data capture (CDC) platform also on MSK. He previously worked on the team that built Klaviyo’s event gateway on Amazon MSK Express, the system described in this post.

Jason Palmer

Jason Palmer

Jason is a Senior Technical Account Manager (TAM) at AWS Enterprise Support, based in Seattle, Washington. With over 6 years at AWS, Jason combines deep technical expertise with a genuine passion for people — helping enterprise customers transform complex challenges into scalable cloud solutions.

Mazrim Mehrtens

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

How Country Road Group built a pattern-driven integration solution on AWS

Post Syndicated from Aman Sharma original https://aws.amazon.com/blogs/architecture/how-country-road-group-built-a-pattern-driven-integration-solution-on-aws/

Are you an integration architect, platform lead, or engineering manager spending a considerable amount on middleware licenses only to move data between systems? This post shows how Country Road Group replaced that middleware with a pattern-driven integration solution on AWS.

Enterprise integration solutions like BizTalk, MuleSoft, TIBCO and Boomi solved the right problem when they emerged. But they also tightly coupled applications to the middleware itself, through proprietary adapters, orchestrations, and message formats. That coupling has become a major source of cost and pain. Many organizations now pay hundreds of thousands per year in licensing, hosting, and maintenance for middleware that delivers no new capability. Meanwhile, the talent to maintain it disappears from the market. The interfaces themselves haven’t changed: publish-subscribe, content-based routing, request-reply, scatter-gather. Cloud-native services now implement them directly, without requiring a middleware runtime in between.

Country Road Group (CRG) is a major Australian fashion retailer operating five brands (Country Road, Mimco, Witchery, Politix, and Trenery) across more than 600 stores. CRG faced exactly this problem. Their 21 integration interfaces ran on Microsoft BizTalk Server hosted on VMware, connecting point-of-sale systems, Oracle RMS databases, and ecommerce platforms. BizTalk was approaching end-of-support. VMware costs were escalating post-Broadcom acquisition. And the team couldn’t hire BizTalk developers anymore.

In this post, we walk through CRG’s Strategic Integration Platform (SIP) and the declarative, pattern-led approach behind it. Rather than writing orchestration code for each interface, CRG’s teams declare which integration pattern an interface uses, and pre-built Terraform modules provision the infrastructure behind it. We cover the four processing lanes that replaced BizTalk and the custom Error Management System that handles failures across them.

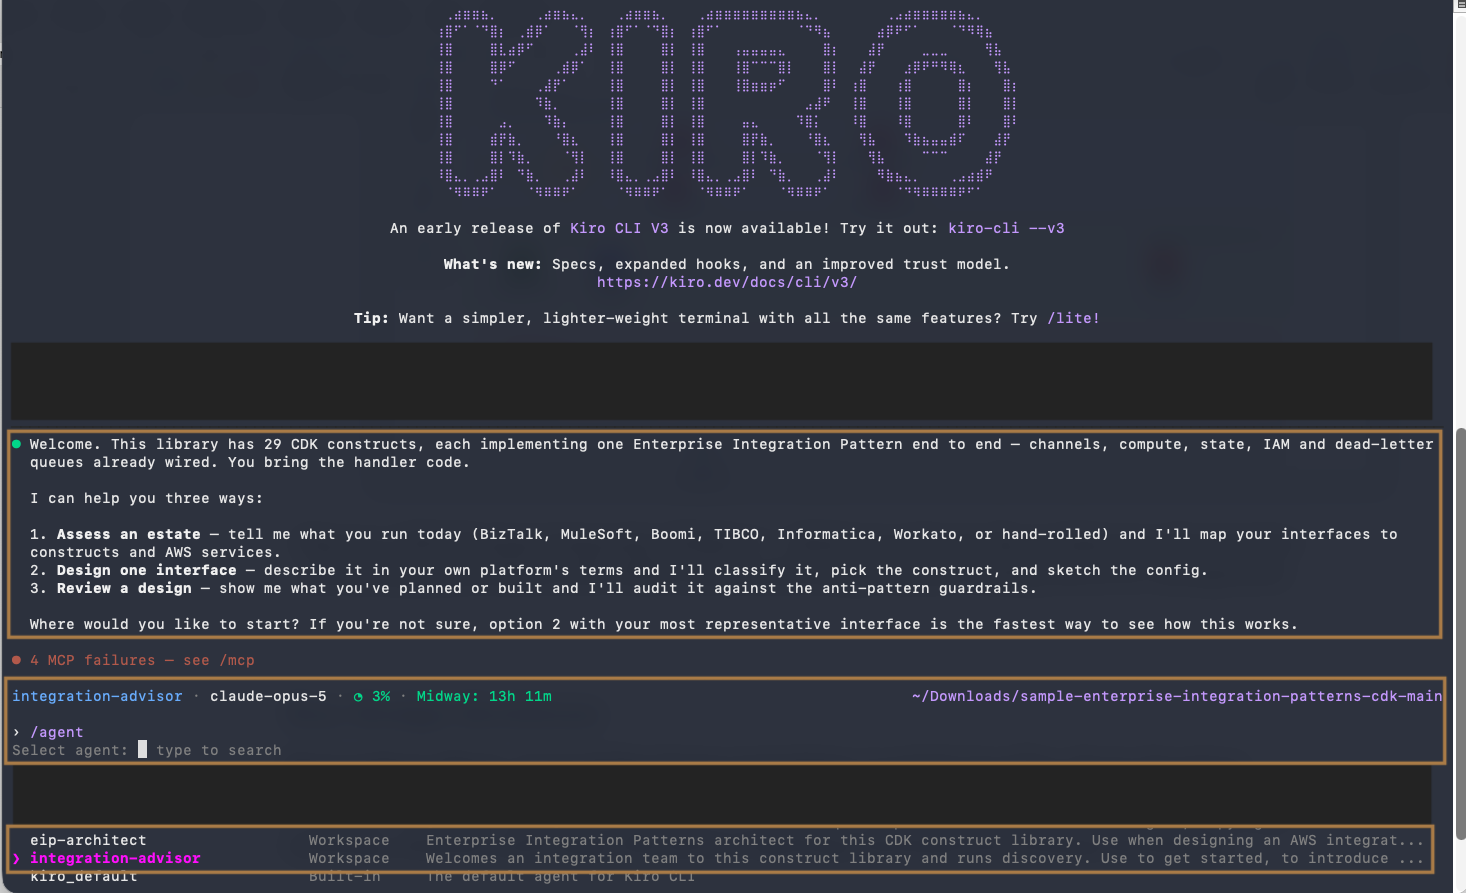
The approach doesn’t depend on any one infrastructure-as-code tool. To help your team adopt it, we’re also releasing a starter kit: the Enterprise Integration Patterns AWS Cloud Development Kit (AWS CDK) Library. It’s an open-source set of 29 constructs that implement the same patterns as reusable infrastructure. Teams using Terraform can use it as a reference implementation. The kit includes an agent skill that helps AI coding assistants such as Kiro and Claude Code select, configure, and compose the right pattern.

Why CRG built SIP

CRG’s existing integration ecosystem suffered from tool sprawl and the presence of end-of-life middleware (BizTalk 2013), leading to increased production instability and operational overhead.

SIP addressed four key value drivers

Legacy debt: Decommission BizTalk 2013 and its unsupported VMware/Broadcom infrastructure.

Tool sprawl: Consolidate BizTalk, Workato, Apollo, and Kafka into a single integration solution with one engineering skillset.

Low velocity: Adopt API-first and continuous integration and continuous delivery (CI/CD) patterns to accelerate new partner integrations.

Security and resiliency risk: Standardize authentication and authorization across every interface and treat dead-letter queues (DLQs) as data stores. Failed messages hold full copies of customer payloads, so DLQs need the same encryption, retention, and access controls as the primary channel to stay within data residency and retention requirements.

SIP architecture overview

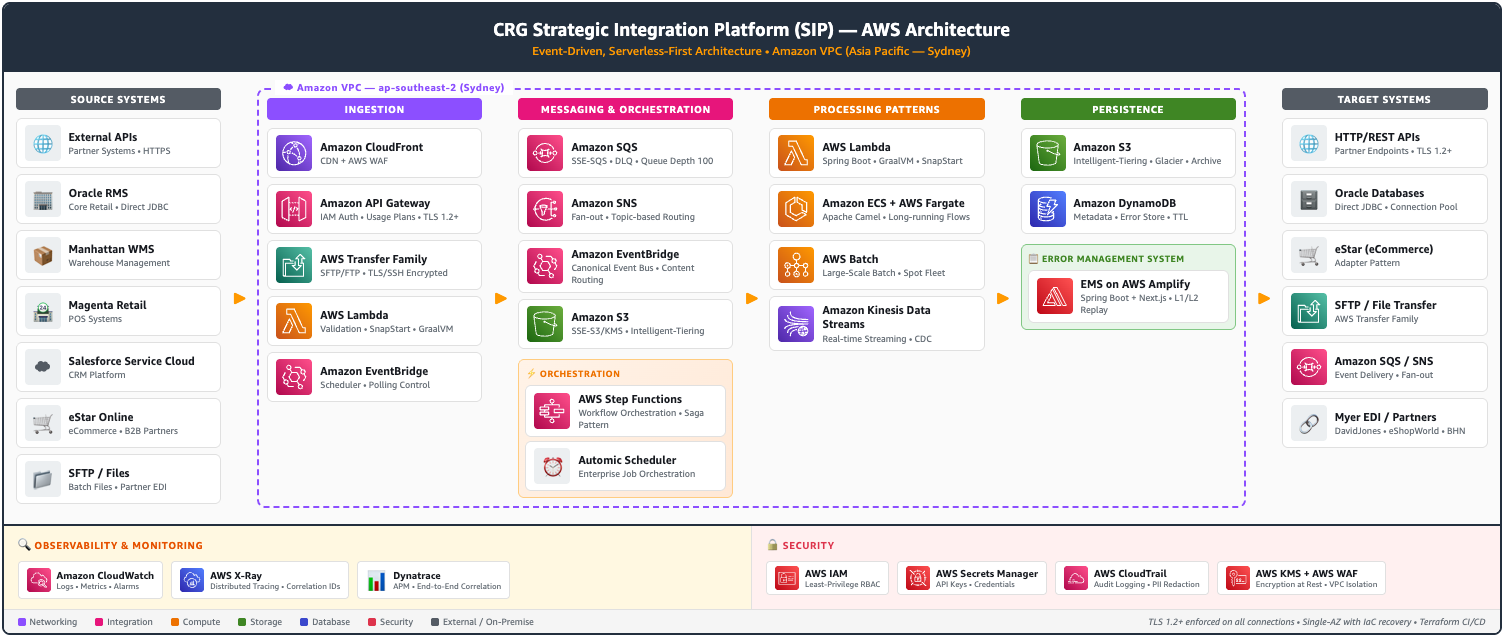
The SIP follows a “Compose on Cloud-Native” strategy. It combines AWS serverless compute (Spring Boot on AWS Lambda, AWS Step Functions, Amazon EventBridge) with Apache Camel on Amazon Elastic Container Service (Amazon ECS) with AWS Fargate for long-running and stateful flows.

The architecture is organized into three layers as shown in Figure 1: a pattern layer where each interface is composed from standardized integration patterns, an AWS service layer where Terraform and CI/CD templates provision and govern infrastructure, and a source-and-target connectivity layer bridging on-premises, cloud, and B2B endpoints.

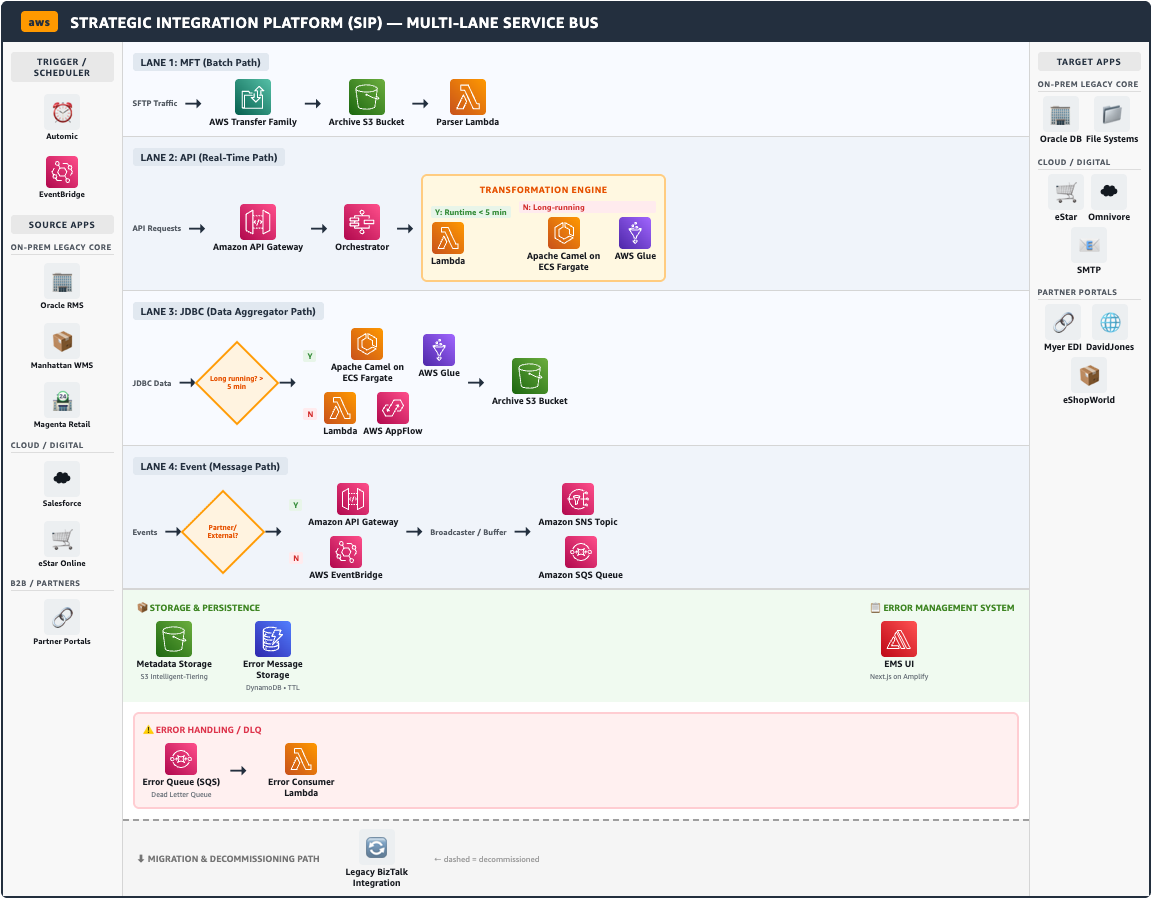
Traffic flows through a four-lane, pattern-led service bus (batch, API, JDBC, and event), as shown in Figure 2. Each lane routes to the appropriate compute runtime based on payload characteristics and processing duration.

Three-layer SIP architecture with a pattern layer, an AWS service layer, and a source-and-target connectivity layer

Figure 1: CRG strategic integration solution — key building blocks

  1. Pattern layer: Each of the 21 interfaces is expressed as a composition of standardized integration patterns (publish-subscribe, content-based routing, and others). This layer contains the business-specific logic: Lambda handlers that validate, transform, and route payloads, orchestrated by Step Functions for multi-step workflows and triggered by Amazon EventBridge rules or Automic. The patterns act as a shared vocabulary across the engineering team. Deployment of an interface starts by selecting a declarative pattern or Terraform code, not by writing infrastructure from scratch.
  2. AWS service layer: The solution provisions its integration surface from AWS managed services, grouped by role. Amazon API Gateway is the entry point, with AWS WAF shielding and rate limiting in front. AWS Lambda handles stateless event processing, and AWS Step Functions orchestrates multi-step workflows with standardized retry and catch logic. Amazon EventBridge is the canonical event bus, with Amazon Simple Queue Service (Amazon SQS) and Amazon Simple Notification Service (Amazon SNS) providing asynchronous buffering and fan-out. Amazon Simple Storage Service (Amazon S3) persists messages, using S3 Intelligent-Tiering and archival to Amazon S3 Glacier storage classes. AWS Transfer Family provides managed SFTP and FTP endpoints. Amazon ECS with AWS Fargate runs Apache Camel routes for long-running flows, and Amazon DynamoDB holds metadata and the error index. Terraform is the authoritative provisioning engine for every AWS resource.
  3. Source and target connectivity layer: On the source side, SIP integrates with on-premises, OCI, legacy core applications (Oracle RMS, Manhattan WMS, Magenta Retail), cloud and digital platforms (Salesforce Service Cloud, eStar Online), and B2B partner portals. On the target side, flows deliver to Oracle databases, eStar (ecommerce), file systems, and partner endpoints.

Note: SIP pulls. Sources don’t push. SIP retrieves data from source systems on its own schedule rather than accepting unbounded pushes. The consumer, not the producer, controls the rate. Where pull doesn’t fit: Some sources can only push, such as SaaS webhooks. In those cases, SIP accepts the push into a queue and processes it at its own pace, so the same principle holds.

Multi-lane service bus routing batch, API, JDBC, and event traffic to compute runtimes with error management

Figure 2: CRG Strategic Integration Platform — multi-lane service bus architecture showing four processing paths (batch, API, JDBC, event) with transformation routing and error management

SIP routes traffic through four pattern-led lanes

  • Lane 1 (MFT/Batch) handles file-based ingestion: Automic or Amazon EventBridge triggers AWS Transfer Family to receive SFTP traffic, archive to S3, and hand off to a parser Lambda for validation and transformation.
  • Lane 2 (API/Real-Time): Processes synchronous REST requests through Amazon API Gateway into a Step Functions orchestrator. A transformation engine routes to the appropriate runtime: Lambda for sub-five-minute jobs, or Apache Camel on ECS Fargate for long-running and stateful flows.
  • Lane 3 (JDBC/Data Aggregator): This pattern handles direct database connectivity for bulk extractions, routing through Lambda and Amazon AppFlow for lightweight aggregation or ECS Fargate for heavier workloads.
  • Lane 4 (Event/Message) manages asynchronous flows: External events enter through API Gateway while internal events route through Amazon EventBridge, with Amazon SNS for fan-out broadcasting and Amazon SQS for buffered consumption.

Across all four lanes, the Error Management System (EMS) provides a unified error handling layer. Failed transactions route to a dead letter queue in Amazon SQS. EMS captures the error metadata in DynamoDB and persists the payload in Amazon S3, with every failure carrying a correlation ID and a standardized JSON error contract. It is built on Spring Boot running on Lambda, with a Next.js front end on AWS Amplify.

L1 and L2 operators use the EMS dashboard to inspect, modify, and resubmit failed transactions idempotently, without developer involvement. New interfaces onboard to EMS automatically through a unique interface ID. This moved CRG from developer-led (L4) error recovery to operator-led (L1) first-line resolution.

Key design decisions

Lambda-first, ECS as fallback: Lambda handles short-duration event processing, Apache Camel on ECS Fargate serves long-running, stateful, and large-file flows.

Reproducible infrastructure: Every AWS resource in the platform is defined in Terraform, so any environment can be rebuilt exactly from code. That fixes configuration drift, a bad change, or an accidentally deleted resource, and the same templates stand up a new environment or Region. Terraform state is held in a versioned, access-controlled S3 bucket. Infrastructure as code rebuilds the platform, not its data, so data is protected separately. DynamoDB point-in-time recovery restores tables, S3 versioning restores objects, and dead-letter queues hold failed messages for redrive. Runtime failures such as an Availability Zone outage don’t need a redeploy at all, because Lambda, SQS, DynamoDB, and Step Functions run across multiple Availability Zones by default.

Amazon EventBridge as canonical event bus: All inter-pattern communication flows through Amazon EventBridge for content-based routing, event replay, and native integration with over 200 AWS services.

Five-layer security: AWS Identity and Access Management (IAM) least-privilege role-based access control (RBAC), AWS WAF with virtual private cloud (VPC) isolation, data classification (Public through Restricted), TLS 1.2+ in transit with AWS Key Management Service (AWS KMS) encryption at rest, and structured audit logging with automated personally identifiable information (PII) redaction.

Open source: Enterprise Integration Patterns CDK Library

In this post, we share an open-source AWS CDK construct library that codifies 29 canonical integration patterns as reusable L3 constructs. Each construct provisions messaging infrastructure, IAM permissions, dead-letter queues, and retry logic from a single declaration. Amazon CloudWatch alarms are deliberately left to the consumer, because thresholds and notification targets are environment specific. The library uses TypeScript and AWS CDK. Teams using Terraform or other infrastructure as code tools can reference the patterns and translate to their provisioning framework.

Prerequisites

An AWS account with the AWS CDK bootstrapped in your target AWS Region, Node.js 20 or later, and the AWS CDK CLI v2. Familiarity with TypeScript helps but the examples are short. For Path 2 you also need Kiro or Claude Code.

Getting started

There are two ways to go from a requirement to a deployed pattern. Path 1 is hands-on: you write the construct declaration and run the CDK commands yourself. Path 2 is agent-assisted: the agents shipped in the repository select and configure the construct for you, and you run the final deploy. Both produce the same thing, a small app.ts that instantiates one or more of the 29 library constructs, so the security posture is identical whichever you choose. Start with Path 1 if you already know which pattern you need. Start with Path 2 if you are coming from a legacy platform’s vocabulary and want help mapping it. Both paths begin the same way:

git clone https://github.com/aws-samples/sample-enterprise-integration-patterns-cdk.git
cd sample-enterprise-integration-patterns-cdk
npm ci
npm run build
npm test

The repository is a construct library, not a deployable application: app.ts ships as an empty stub, and cdk synth on a fresh clone produces no stacks by design.

Path 1: Declare a pattern yourself

Open app.ts and declare the construct you need. The README’s Implementation Guide has worked examples for request-reply, publish-subscribe, scatter-gather, and saga. Then synthesize and deploy:

npx cdk synth
npx cdk deploy

Path 2: Let the agents do the selection and configuration

Open the repository in Kiro or Claude Code and select an agent from the chat input. Kiro, the agentic coding IDE and CLI from AWS shown in Figure 3, uses spec-driven development to translate natural-language requirements into pattern compositions. Describe the integration requirement in your own terms, and the agent selects the right construct from the library, writes the declaration into app.ts with correctly configured props, and validates it with npm run build, npm test, and cdk synth. Deployment stays with you: the shipped eip-architect agent is denied cdk deploy and cdk destroy by design, so nothing reaches an account without a human running it. When the agent reports the declaration ready, you run the same two commands as Path 1.

The repository ships two agent skills and two custom agents for this. Use them in order, or go straight to the second if you already know what you are building.

  • integration-advisor runs discovery. It asks the questions, maps each of your existing interfaces to a construct, and writes an assessment file. It touches no code.
  • eip-architect picks that assessment up and writes the CDK declarations that instantiate the right library constructs with the correct configuration for each pattern, then verifies them.
Kiro CLI running the integration-advisor and eip-architect agents

Figure 3: Two agents in action, integration-advisor and eip-architect, running in the Kiro CLI

Clean up

Remove anything you deployed with npx cdk destroy. The constructs default to RemovalPolicy.DESTROY, so queues, tables, and buckets created by a pattern are removed with the stack.

Results

Annual integration service costs dropped from approximately $300,000 to $60,000, an 80 percent saving. Four middleware tools (BizTalk, Workato, Apollo, and Kafka) consolidated to one. The primary objective, full decommissioning of Microsoft BizTalk Server and its associated VMware/Broadcom infrastructure, has been accomplished. CRG now deploys new interfaces through standardized patterns in hours rather than weeks, using cookie-cutter Terraform templates and automated CI/CD pipelines. The Error Management System shifted failure resolution from engineering to L1 operators, fundamentally changing the support cost model. Distributed telemetry across Amazon CloudWatch, AWS X-Ray, and Dynatrace provides end-to-end transaction tracing with correlation IDs through every integration hop. CRG migrated interfaces in waves grouped by business function, with service-group rollback allowing any failed wave to revert independently. The architecture is cloud-native by design: because the pattern layer is decoupled from the service layer, you can incorporate new AWS services as steps within any existing pattern composition without re-architecting the platform.

Conclusion

For organizations retiring legacy middleware or designing integrations from scratch, the goal is the same: a modern, decoupled architecture where systems exchange data through well-understood patterns, not through a central runtime they all depend on. CRG’s approach offers a replicable playbook. Legacy integration middleware carries compounding costs: licensing, hosting, scarce talent, and opportunity cost from slow delivery cycles. A pattern-driven migration on cloud-native services addresses all four simultaneously. The open-source AWS CDK construct library and Kiro agent skill published alongside this post give your team a head start, packaging the patterns CRG proved in production. Whether you run BizTalk, MuleSoft, TIBCO, or Boomi, the integration patterns are the same. Only the execution layer changes.


About the authors

Aman Sharma

Aman Sharma

Aman is an Enterprise Solutions Architect at AWS, partnering with retail and supply chain customers across ANZ to drive business value and transformative outcomes. With over 21 years of experience in consulting, cloud native architectures, integration patterns, data center exit, migration, modernization, and data platform modernization. He is also passionate about democratizing AI, ML, and agentic development, helping customers build purposeful, high-impact solutions. Outside of work, he enjoys nature, music, and wildlife photography.

Andrew Hooker

Andrew Hooker

Andrew is a Principal Solutions Architect at Amazon Web Services, based in Melbourne, Australia. With close to 20 years of experience across software engineering, architecture, and technical leadership, he works with some of Australia’s largest enterprises on AI strategy, cloud architecture, and engineering transformation. Andrew is a thought leader in agentic AI, the AI software development lifecycle, and software engineering automation, helping organizations rethink how their teams build software in an AI-augmented world. He also specializes in serverless architecture and event-driven integration patterns, modernizing how enterprise systems connect and scale. His work spans AI agent orchestration, AI governance and observability, integration framework design, serverless and event-driven architectures, enterprise platform modernization, and applied AI in regulated industries. He has a deep interest in graph databases and their role in knowledge-driven systems.

Vijay Krishnaswamy

Vijay Krishnaswamy

Vijay is an Enterprise Architect at Country Road Group, where he owns the Customer, Retail and Digital domains across five retail brands. His 20+ years span enterprise integration, data modelling, migration and platform architecture. He was a key architect in replacing a legacy BizTalk iPaaS estate with AWS-native services, and designed the customer, order and loyalty data migration onto AWS for the group’s commerce replatform. He works close to the code, on the view that an architecture is only proven by what it does in production. Outside of work, he enjoys spending time in nature and playing badminton.

Rakesh Sahu

Rakesh Sahu

Rakesh is the Platform Owner – Data Integration & Automation, responsible for defining and delivering the platform strategy, architecture, and roadmap that enable scalable integration and automation capabilities across the organization. He leads the delivery of enterprise solutions spanning system integrations, APIs, cloud services, data platforms, and business process automation, ensuring reliability, security, and operational excellence. He partners with business and technology stakeholders to drive digital transformation initiatives, simplify complex integrations, optimize platform investments, and deliver measurable business outcomes. His expertise includes enterprise integrations, cloud technologies, automation, API-led connectivity, and large-scale platform implementations.

Tim O’Sullivan

Tim O’Sullivan

Tim is an Enterprise Account Manager at Amazon Web Services (AWS), specialising in Retail and Supply Chain. Based in Melbourne, Tim brings more than 25 years of experience in technology and is a trusted adviser to Australia’s leading retailers on transformation, from unified commerce and data to agentic AI. He works with executive teams to turn cloud and AI into real growth, better customer experiences and operational efficiency. Tim is also an active mentor in the AWS She Builds Mentorship Program, championing diversity in tech.

What’s new in AWS Transform – continuous modernization for re:Invent 2026

Post Syndicated from Nithin Moorthy original https://aws.amazon.com/blogs/devops/whats-new-in-aws-transform-continuous-modernization-for-reinvent-2026/

Since general availability in August 2026, platform teams have used continuous modernization through AWS Transform to keep tech debt from piling up. To see what customers have achieved, read the success stories on the AWS Transform – continuous modernization page.

Ahead of re:Invent 2026, we’re making the experience faster to start, easier to act on, and easier to extend. Setup takes a few steps, each issue shows up once across your estate, and remediations arrive as one pull request per repository. You can now bring your own skills (transformation definitions), have one generated when none fits, and ask chat about your estate or have it act for you. A new integration with AWS Health takes you from a planned lifecycle event (PLE), such as an AWS Lambda runtime reaching end of support, straight to the affected code.

Get started in a few steps

Getting your first findings used to mean creating personal access tokens, configuring AWS Identity and Access Management (IAM) roles, and picking analyses before you saw any findings.

Continuous modernization now connects to GitHub, GitLab, and Bitbucket through OAuth, so there are no tokens to manage. It also creates its execution role for you during onboarding.

As soon as your repositories are connected, continuous modernization recommends analyses for your estate. These include comprehensive tech debt for outdated dependencies and end-of-support runtimes, or modernization readiness for repositories that could move to containers or serverless. You choose which ones to run, and recommended analyses are scheduled by default, so your findings stay current without anyone rerunning them.

The continuous modernization Get started page, which connects your source and turns on recommended analyses.

Figure 1: The continuous modernization Get started page, which connects your source and turns on recommended analyses.

Recommended analyses scheduled to run automatically after you connect your source.

Figure 2: Recommended analyses scheduled to run automatically after you connect your source.

Start from what AWS Health already knows

AWS Health notifies you about planned lifecycle events (PLEs) that affect your account, such as a Lambda runtime reaching end of support or an Amazon Elastic Kubernetes Service (Amazon EKS) version upgrade. It tells you what’s changing and by when. Continuous modernization now integrates with AWS Health to find and fix the affected code.

Planned lifecycle events from AWS Health, grouped by change deadline

Figure 3: Planned lifecycle events from AWS Health, grouped by change deadline

Findings from the AWS Health analysis, each mapped to a recommended transformation

Figure 4: Findings from the AWS Health analysis, each mapped to a recommended transformation

Continuous modernization maps each PLE to the affected repositories and findings. For most PLEs, one remediation covers every affected repository. It applies the matching skill, such as an AWS managed Lambda runtime upgrade, and opens one pull request per repository. The deadline and affected resources stay with the work, so you can track each PLE until it’s cleared.

The integration uses the AWS Health API, which requires AWS Business Support+, AWS Enterprise Support, or AWS Unified Operations. In Regions without these plans, Business, Enterprise On-Ramp, or Enterprise Support also works. For details, see Integrating AWS Health with other systems using the AWS Health API.

Know exactly what to tackle first across your organization

Until now, an issue showed up as a separate finding in every repository it touched, so dozens of repositories using the same deprecated library meant dozens of findings to triage.

The redesigned Findings page grouping each issue with its affected repositories, severity, and recommendation

Figure 5: The redesigned Findings page grouping each issue with its affected repositories, severity, and recommendation

Continuous modernization now groups findings that share an underlying issue, so each issue appears once with every affected repository listed under it. On the redesigned Findings page, each group shows its severity, scope, safety bar status, and recommended AWS managed transformation or specialized skill. Select the groups you want to fix and choose Create remediation plan.

Resolve issues across your organization in one pass

Until now, each finding was remediated in its own pull request, so a repository with five findings meant five pull requests.

Now you can remediate a group of findings together, whether continuous modernization created the group or you did. It combines each repository’s findings into a single pull request, so app teams review and merge once per repository instead of once per finding.

A remediation plan that combines issue groups into one pass with one pull request per repository

Figure 6: A remediation plan that combines issue groups into one pass with one pull request per repository

Remediate with your own skills

Most platform teams have standards that no general-purpose tool knows about, such as an approved logging framework, a required security configuration, or an internal API you’re retiring.

You can now run your own skills from the console, alongside AWS managed ones:

  • Custom analysis scans your repositories against your rules and reports findings. It runs on AWS managed infrastructure or in your own account.
  • Custom remediation applies your skills to resolve those findings. It runs on infrastructure in your own account, such as AWS Batch.
Running a custom analysis and selecting your own transformation definition from the console

Figure 7: Running a custom analysis and selecting your own transformation definition from the console.

When no skill fits, one gets generated

Between AWS managed skills and your own, most findings have a recommended remediation ready. Most estates still have a long tail, such as an internal framework, an unusual build setup, or a library few others use.

When no skill fits a finding, continuous modernization now generates one, and nothing runs until you review the skill and what it will change. Then you choose one of the following options:

  • Use it once to remediate this finding.
  • Publish it to the skills registry in your AWS account, so it’s ready the next time the issue appears.
A generated skill shown with its target, approach, and validation for review before anything runs

Figure 8: A generated skill shown with its target, approach, and validation for review before anything runs

Ask about your estate in plain language

Not every question fits a filter. In chat, you can ask about your findings, analyses, and remediations in plain language. For example:

  • “What changed since the last analysis?”
  • “Why did the remediation on checkout-service fail?”
  • “Plan my week.” Chat summarizes failed work to unblock, remediations ready to start, and findings with no automated remediation.

Chat can also take action: start or schedule an analysis, start a remediation and check its progress, or dismiss findings in bulk. Every action shows a confirmation card first and runs with your own permissions. To ask about something specific, choose Ask about this on any finding, analysis, or remediation.

Chat answering a question about your estate and offering to start the remediation

Figure 9: Chat answering a question about your estate and offering to start the remediation

Take your results anywhere

You can now download the artifacts from any analysis, such as its report. Share them with stakeholders, keep them as audit and compliance evidence, or feed them into your own dashboards and ticketing tools.

See it in action at re:Invent 2026

Try these new features today, and then join us in Las Vegas to see them live and talk with the team. Choose a session ID for times and repeats.

  • MAM230 (breakout): From CI/CD to CI/CD/CM: Continuous modernization for AI-generated code.
  • MAM350 (code talk): Continuous tech debt analysis and remediation, from findings to fixes.
  • MAM344 (breakout): From migration to continuous modernization: reduce tech debt at scale.
  • DVT309 (workshop): Your runtime is being deprecated. Your weekend isn’t.
  • DVT323 (chalk talk): Tech debt anonymous: bring your worst code to this chalk talk.
  • MAM205 (chalk talk): Move code modernization at scale from one-time to continuous.
  • DVT301 (builders’ session): Bring your tech debt: build a custom transformation that fixes it.

Get started

Tech debt builds up one outdated dependency at a time. Continuous modernization now sets up in a few steps, shows each issue once, fixes it in one pull request per repository, and starts from what AWS Health already knows. To get started, use the following resources:

Have an AWS Health event waiting? Open Scheduled changes in the AWS Health Dashboard and choose Upgrade with Continuous Modernization.


About the authors

Nithin Moorthy

Nithin Moorthy

Nithin is a Senior Product Manager–Technical at AWS working on AWS Transform custom and continuous modernization. Both use agentic AI to help developers modernize code across their entire application portfolio. Nithin focuses on helping customers modernize their applications faster and keep them current over time.

Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan (Venu) is a Principal Specialist Solutions Architect at AWS. He leads generative AI initiatives across the AI-driven software development lifecycle, agentic AI for application modernization, and frontier engineering, with a focus on Kiro and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to ship faster and keep their applications current.

Announcing in-place upgrades from Standard brokers to Express brokers for Amazon MSK

Post Syndicated from Ankita Mishra original https://aws.amazon.com/blogs/big-data/announcing-in-place-upgrades-from-standard-brokers-to-express-brokers-for-amazon-msk/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) now supports in-place upgrades from Standard brokers to Express brokers. With in-place upgrade, you can modernize your existing MSK Provisioned cluster to Express brokers through a fully managed workflow, designed to minimize application changes while helping to maintain high availability throughout. Express brokers deliver increased stability at higher throughputs, scale up to 20 times faster, and recover up to 90% faster than standard Apache Kafka brokers. The in-place upgrade is a direct path to those benefits. Until now, adopting Express brokers meant standing up a new MSK Provisioned cluster and migrating both your data and your applications to it. That cut-over added weeks or months of cross-team coordination and put application availability at risk. The in-place upgrade removes that work entirely. Amazon MSK modernizes your existing cluster to Express brokers through a fully managed workflow, with no new cluster, no application changes, and no downtime, turning a multi-month migration into a few hours.

With the in-place upgrade, Amazon MSK adds Express brokers to your existing cluster and moves topics for you, preserving both the cluster endpoint and your Kafka topic offsets. As partitions move, MSK reassigns their replicas to the Express brokers and transfers partition leadership through Kafka’s standard leader-election process. Producers and consumers continue using the same topics and the same cluster endpoint without interruption. Applications can continue serving traffic throughout the migration, delivering a zero-downtime client experience. Because the upgrade uses Kafka-native protocols that preserve topic offsets, your stateless and stateful applications (including Apache Flink and Kafka Streams) can resume from their exact position, with no reprocessing, errors, or duplicates. The upgrade can be reversed until you decommission the Standard brokers, keeping you in control throughout the process.

Prerequisites

In-place upgrade to Express brokers is available for MSK Provisioned clusters configured with Standard brokers, in all AWS Regions where MSK Express brokers are supported. Before you begin, confirm your cluster meets the following requirements. These are also validated when you assess upgrade readiness with the API, described in the next section:

  • Kafka version: The cluster must run Apache Kafka version 3.9 with KRaft metadata management.
  • Three Availability Zones: The cluster must be deployed across three Availability Zones.
  • No tiered storage support: Clusters with tiered storage enabled are not supported.
  • Topic and broker configuration requirements: Express brokers enforce a set of best-practice configurations to maintain stability and high availability. Before initiating upgrade, confirm your cluster meets the following Express requirements:
    • replication.factor=3.
    • min.insync.replicas=2.
    • unclean.leader.election.enable = false.
    • segment.ms set to at least 60,000 milliseconds.
    • max.message.bytes set to no more than 8 MiB.
    • max.compaction.lag.ms set to at least 24 hours.
    • A supported broker instance type.
    • Per-broker partition counts within the Express broker partition quota.

The upgrade process

The following steps use the AWS Command Line Interface (AWS CLI). You can also perform them programmatically with the AWS Management Console or SDK. To perform the upgrade with an AI agent, use the managing-amazon-msk Agent Skill, which powers agents to manage the upgrade process end to end. All sections of this post can be automated with the managing-amazon-msk Agent Skill.

You can upgrade your existing Standard brokers on M5, M7g or M8g instances to Express brokers on M7g or M8g instances. Express brokers on AWS Graviton4-based M8g instances deliver up to 15% lower compute costs, up to 45% lower P99 produce latency, and 2x faster recovery when consumers fall behind, than Express brokers on M7g. You also no longer pay the broker-side cost when moving data across Availability Zones, which reduces total cross-AZ data transfer costs by 50%.

Pre-upgrade: Assess upgrade readiness

To confirm your cluster is ready for in-place upgrade to Express brokers, use the CreateAssessment API. The assessment validates your broker and topic configurations against Express requirements and returns its findings, including any changes to make first. Address any changes that the assessment flags as blockers before you initiate the upgrade. When you initiate the upgrade, MSK automatically re-validates your configuration and proceeds only after all checks pass.

Create the assessment

To create an assessment, specify the target Express instance type. Express brokers are available in the M7g and M8g instance families. You choose the family, and the upgrade keeps your broker size and broker count. For example, if you are on Standard kafka.m5.large, specify express.m7g.large or express.m8g.large. Clusters with Standard brokers on M8g instances can also upgrade to Express brokers on M8g instances:

aws kafka create-assessment \
--region "$AWS_REGION" \
--cluster-arn "$CLUSTER_ARN" \
--assessment-type UPDATE_BROKER_TYPE \
--assessment-parameters TargetInstanceType=express.m8g.large

Check the assessment status

To check the assessment status, use the following and wait until Status shows COMPLETE (assessments typically finish in about two minutes):

aws kafka describe-assessment \
--region "$AWS_REGION" \
--cluster-arn "$CLUSTER_ARN" \
--assessment-arn "$ASSESSMENT_ARN"

List assessment findings

To read the findings after the assessment is complete, use:

aws kafka list-assessment-findings \
--region "$AWS_REGION" \
--cluster-arn "$CLUSTER_ARN" \
--assessment-arn "$ASSESSMENT_ARN"

ERROR findings are blocking and must be resolved before initiating the upgrade. WARNING and INFO findings are informational. Resolve any blocking findings before continuing.

Performing the upgrade

The in-place upgrade to Express brokers is a managed workflow that you drive at your own pace.

Step 1: Initiate the upgrade

To initiate the upgrade using the CLI, use the UpdateBrokerType API. It takes four inputs:

  • --cluster-arn, the ARN of the cluster you’re upgrading.
  • --current-version, the cluster’s current version (to get it, use the DescribeCluster API).
  • --target-instance-type, a combined string naming your current Standard instance type and the target Express instance type, joined with a hyphen. For example, to upgrade a cluster from kafka.m7g.large Standard brokers to express.m8g.large Express brokers, set the target to kafka.m7g.large-express.m8g.large.
  • --topic-reassignment, how to move topics to Express brokers:
    • AUTO: Amazon MSK manages the topic migration for you. It validates your configuration, provisions Express brokers matching the count and size of your Standard brokers and moves every topic from Standard to Express in safe, managed batches. Your applications keep producing and consuming against the same cluster endpoint throughout. After all topics are on Express and you have validated your applications, you complete the upgrade to decommission the Standard brokers.
    • MANUAL: Amazon MSK provisions the Express brokers but moves no topics until you reassign them yourself, giving you a controlled, topic-by-topic experience. You move and validate topics at your own pace, as described in Step 2.

For example:

aws kafka update-broker-type \
--cluster-arn "$CLUSTER_ARN" \
--current-version "$CURRENT_VERSION" \
--target-instance-type "$TARGET_INSTANCE" \
--topic-reassignment AUTO

Step 2: Move topics (controlled mode only)

When you initiate in controlled mode (--topic-reassignment MANUAL), MSK adds the Express brokers but moves no topics until you drive the reassignments. Wait until the cluster returns to Active with both Standard and Express brokers. Then move topics with the StartTopicReassignment API.

You can selectively move topics with the --topics-to-include and --topics-to-exclude wildcard patterns, and set the direction with --target-instance-type. To move topics to Express brokers, pass your Express instance type ($EXPRESS_INSTANCE, for example express.m8g.large). To move topics back to your Standard brokers, pass your Standard instance type ($STANDARD_INSTANCE, for example kafka.m7g.large). Start with lower-risk topics, validate application performance on Express, then continue.

To complete a migration, all topics (including internal topics) must be moved to the Express brokers. After you finish testing with application topics, confirm you also move internal topics to Express brokers.

Move a specific set of topics onto Express:

For example, to move the orders.* topics to Express brokers:

aws kafka start-topic-reassignment \
--cluster-arn "$CLUSTER_ARN" \
--target-instance-type "$EXPRESS_INSTANCE" \
--topics-to-include 'orders.*'

This moves every topic whose name matches the include pattern onto Express brokers. Patterns are regular expressions, so orders.* can match many topics. It does not name a single topic.

Hold specific topics back from Express:

To move all orders.* topics except the payments topics to Express brokers:

aws kafka start-topic-reassignment \
--cluster-arn "$CLUSTER_ARN" \
--target-instance-type "$EXPRESS_INSTANCE" \
--topics-to-include 'orders.*' \
--topics-to-exclude 'orders\.payments.*'

This moves topics such as orders.created and orders.shipped onto Express, and the orders.payments topics stay on Standard. MSK applies the exclude patterns after the include patterns, so a topic that matches both stays where it is. You can move the held-back topics later in a separate reassignment.

Move all topics at once:

You can also move all topics at once to Express brokers. This is useful if you’ve tested a subset of topics on Express, and are ready to complete moving the remaining topics:

aws kafka start-topic-reassignment \
--cluster-arn "$CLUSTER_ARN" \
--target-instance-type "$EXPRESS_INSTANCE" \
--topics-to-include '.*'

This broad include pattern moves every topic, you can narrow the pattern (or exclude) to move topics incrementally.

Stop in-flight reassignment:

To stop a reassignment, you need its topic reassignment operation ARN. The StartTopicReassignment API returns it in the response. You can also get it from the ListTopicReassignments API, which lists every reassignment on the cluster with its operation ARN and status.

aws kafka list-topic-reassignments --cluster-arn "$CLUSTER_ARN"

Pass the ARN to stop-topic-reassignment:

aws kafka stop-topic-reassignment \
--cluster-arn "$CLUSTER_ARN" \
--topic-reassignment-operation-arn "$OP_ARN"

This stops the in-progress reassignment identified by its operation ARN. Topics that already moved stay on Express brokers. Only one reassignment can run on a cluster at a time, so wait until list-topic-reassignments shows the status as STOPPED. Then start a new reassignment with the same start-topic-reassignment command and patterns you used before. The new reassignment gets its own operation ARN, so use that new ARN if you need to stop it later. To move topics back to Standard instead, set --target-instance-type to $STANDARD_INSTANCE, as shown in the following rollback example.

Roll back process:

To roll back a set of topics by name or wildcard, pass the Standard instance type (for example, kafka.m7g.large) in the --target-instance-type:

aws kafka start-topic-reassignment \
--cluster-arn "$CLUSTER_ARN" \
--target-instance-type "$STANDARD_INSTANCE" \
--topics-to-include 'orders.*'

Targeting the Standard instance type moves the matching topics back to Standard while the rest stay on Express. Move topics again after the issue is resolved and you’re ready to move the topics back to Express. To roll back all topics from Express brokers to Standard brokers, first use the StartTopicReassignment API with .* as the topic wildcard and your Standard instance type as the target instance type:

aws kafka start-topic-reassignment \
--cluster-arn "$CLUSTER_ARN" \
--target-instance-type "$STANDARD_INSTANCE" \
--topics-to-include '.*'

Then, decommission the Express brokers by calling UpdateBrokerType with the Standard instance type as the target instance type:

aws kafka update-broker-type \
--cluster-arn "$CLUSTER_ARN" \
--current-version "$CURRENT_VERSION" \
--target-instance-type "$STANDARD_INSTANCE"

Step 3: Monitor progress

Track the overall upgrade on the Cluster operations tab on the console, or with the DescribeClusterOperation API, passing the operation ARN returned by update-broker-type. In Amazon CloudWatch, graph PartitionCount, BytesInPerSec, and BytesOutPerSec by broker ID to watch partitions and throughput shift from the Standard brokers to the Express brokers.

To check whether the upgrade operation is in progress, complete, or failed, use:

aws kafka describe-cluster-operation --cluster-operation-arn "$OPERATION_ARN"

To show migration progress per topic, so you can see which topics have moved to Express and which are still in flight, use:

aws kafka list-topic-reassignments --cluster-arn "$CLUSTER_ARN"

To list each broker node with its BrokerNodeType, so you can identify which brokers are Standard and which are Express as leadership shifts, use:

aws kafka list-nodes --cluster-arn "$CLUSTER_ARN"

The upgrade takes a few hours depending on cluster size and data volume.

Step 4: Validate applications on Express

After every topic has moved to Express brokers, check your workload before you complete the upgrade. The Standard brokers stay in the cluster during this step, so you can still move topics back to them if you find an issue.

To confirm that all partitions have moved, run list-topic-reassignments. Then check that LeaderCount is 0 on every Standard broker. After that:

  • Verify that topics, partitions, and consumer groups are present.
  • Confirm cluster health: ActiveControllerCount is 1 and OfflinePartitionsCount is 0.
  • Confirm producer and consumer throughput and performance align with pre-upgrade baselines.
  • Confirm stateful applications (for example, Apache Flink and Kafka Streams) remain healthy and continue processing after partition leadership moves to Express brokers.

If a topic has problems, move it back to Standard with the rollback commands in Step 2. Run this check for at least one full processing cycle of your workload before you continue.

Step 5: Complete the upgrade

MSK waits for you to confirm before it removes the Standard brokers. When your validation is done, choose Complete Upgrade on the console, or call UpdateBrokerType again with only the Express instance type:

aws kafka update-broker-type \
--cluster-arn "$CLUSTER_ARN" \
--current-version "$CURRENT_VERSION" \
--target-instance-type "$EXPRESS_INSTANCE"

Amazon MSK decommissions the Standard brokers, and the cluster returns to the ACTIVE state as an Express-only cluster. This step is final: once the Standard brokers are removed, reverting to Standard requires creating a new cluster and migrating to it with Amazon MSK Replicator. After the upgrade completes, update or retire any monitoring alerts and dashboards that are specific to your former Standard brokers.

Step 6: Post-upgrade optimization

After the upgrade, intelligent rebalancing is paused on your cluster. New Express clusters have it turned on by default, but upgraded clusters do not. With intelligent rebalancing, you can scale your clusters up or down by editing the broker count in your clusters in a single action, and Amazon MSK will keep partitions evenly distributed across brokers. Because MSK provisions one Express broker for each Standard broker, your cluster may have more capacity than your workload needs. Turn on intelligent rebalancing first, then use your post-upgrade metrics to right-size the cluster by reducing the broker count or changing the instance size as required.

Additionally, Express brokers surface an improved bootstrap endpoint for client connections. The boot-XXX.clustername.kafka.us-east-1.amazonaws.com endpoints are managed by MSK Express and improve distribution of connections for metadata requests across your brokers. You can update applications to use these new endpoints at any time to improve reliability and connection distribution. Your applications configured with broker ID-based bootstrap endpoints (for example, b-1.clustername.kafka.us-east-1.amazonaws.com) will continue to function after the upgrade, so this step is optional.

Additional considerations

Beyond these prerequisites, plan for the following during the upgrade window:

  • Billing: During the upgrade, MSK adds Express brokers to your existing cluster, matching the size and count of your Standard brokers. For example, for a cluster with 3 kafka.m5.large Standard brokers MSK adds 3 express.m7g.large Express brokers during the upgrade. Because both broker sets are provisioned throughout the upgrade period, you are charged for both broker types until the upgrade completes. There is no additional charge for the upgrade itself.
  • Restricted operations: Some cluster modification operations, such as version upgrades, broker configuration changes, and authentication or monitoring changes, are blocked during the upgrade to prevent configuration mismatches between broker types. Kafka read and write, topic create and delete, and broker reboots continue to work. MSK pauses migration during scaling operations and resumes automatically afterward.
  • Monitoring metrics: Standard and Express brokers emit different CloudWatch metrics. Plan to update dashboards and alarms as topics move to Express. In particular, replace KafkaDataLogsDiskUsed with StorageUsed, and retire Amazon Elastic Block Store (Amazon EBS) storage metrics such as BurstBalance.

Get started with Express brokers on Amazon MSK

The in-place upgrade from Standard brokers to Express brokers gives you a straightforward path to the performance, faster scaling, and lower operational overhead of Express brokers, without application changes, cross-team coordination, or reprocessing state. Amazon MSK handles the broker provisioning, topic movement, and offset preservation for you, whether you let MSK move every topic automatically or move topic by topic. What used to take months of migration effort can now complete in hours.

To move even faster, you can use the managing-amazon-msk skill with your AI coding agent (such as Kiro or any MCP-compatible agent) through the AWS MCP server. The skill assesses your cluster’s compatibility with Express requirements and provides commands to resolve any issues, generates a proof-of-concept package to validate Express performance for your workload, and recommends a right-sized Express cluster footprint.

In-place upgrade to Express brokers is available for MSK Provisioned clusters configured with Standard brokers, in all AWS Regions where MSK Express brokers are supported. To get started, see the Amazon MSK Developer Guide.


About the authors

Ankita Mishra

Ankita Mishra

Ankita is a Product Manager for Amazon Managed Streaming for Apache Kafka. She works closely with AWS customers to understand their needs for real-time analytics and high throughput, low latency streaming workloads. Working backwards from their needs, she helps drive the MSK roadmap and deliver new innovations that help AWS customers focus on building novel streaming applications.

Ravindranath Kakarla

Ravindranath Kakarla

Ravindranath is a Senior Software Development Engineer for Amazon Managed Streaming for Apache Kafka. He builds the systems that run customers’ real-time, high-throughput streaming workloads, and recently led the launch of in-place migration from Standard to Express brokers. He also works on cross-region disaster recovery and data distribution, helping customers replicate their streaming data across AWS Regions. Working backwards from customer needs, he focuses on making MSK resilient and simple to operate, so customers can focus on building novel streaming applications.

Ashley Millette

Ashley Millette

Ashley is a Specialist Solutions Architect for Streaming and Analytics at AWS. She partners with customers to design and implement real-time data streaming architectures using services like Amazon MSK helping them build scalable, cost-effective pipelines that turn data in motion into actionable insights. She is passionate about simplifying complex streaming workloads and enabling customers to modernize their data infrastructure with confidence.

Simon Peyer

Simon Peyer

Simon is a Solutions Architect at AWS based in Switzerland. He is a practical doer and passionate about connecting technology and people using AWS Cloud services. A special focus for him is data streaming and automations. Besides work, Simon enjoys his family, the outdoors, and hiking in the mountains.

Your AWS Security, Identity, and Governance guide to re:Invent 2026

Post Syndicated from Brandon Carroll original https://aws.amazon.com/blogs/security/your-aws-security-identity-and-governance-guide-to-reinvent-2026/

The AWS Security, Identity, and Governance team invites you to join us at re:Invent in Las Vegas from November 30 to December 4, 2026. You know all too well that AI agents now act on their own across the systems you run, and that changes what identity, detection, network protection, and governance have to cover. re:Invent is the week to see how AWS is building security for that shift and to talk it through with the people building it.

Security sessions run every day of the week, nearly 120 of them across breakouts, chalk talks, workshops, code talks, builders’ sessions, and lightning talks. On Thursday, December 3, the Wynn hosts a full day of advanced security sessions in one venue. The sessions are built around five themes this year. They cover securing the agentic enterprise, building securely at the speed you ship, running one security operating model everywhere you run, regulatory confidence and digital sovereignty, and building a culture of security.

Keynotes

AWS leaders use the keynotes to announce new services, launches, and updates that will shape the year ahead in cloud. Many security launches debut during keynote week, and the keynotes set the context for the sessions you’ll attend in the security track. The Thursday keynote runs from 8:30 to 10:00 AM at The Venetian and is also streamed online.

Thursday, December 3: A full day of security deep dives at the Wynn

Security sessions start Monday morning and run through Friday. Thursday is different. 78 security sessions, most of them at the 300 level or above, fill the Wynn from 8:00 AM to 5:30 PM, so you can spend the whole day in one building without crossing the Strip. Rooms are on the Convention Promenade, the Upper and Lower Convention Promenades, and Level 1, and the Cristal 2 Content Hub runs lightning talks and theater sessions all day. The day includes 12 workshops, 11 builders’ sessions, and 22 chalk talks, so most of it is hands-on or interactive.

Three main stage talks from AWS security leaders run through the day in Bandol 1.

Time Talk Speaker
11:00 AM The Future of Security Chet Kapoor, AWS VP of Security, Search, and Observability
1:00 PM The Old Security Playbook Is Dead Amy Herzog, AWS Chief Information Security Officer
3:00 PM Operationalizing security for the future with best practices today Eric Brandwine, VP/Distinguished Engineer, AWS Security

Chet opens with how AWS is building security for a time when systems and threats both move at machine speed, and how customers secure their agent workloads. Amy follows with what happens when the window between a vulnerability existing and being exploited shrinks from years to minutes. She shares how AWS changed its own practices to stop AI-enabled threat actors and what you can change in your own operations. Eric closes the day by showing how to take the latest AWS security innovations from announcement to adoption across your organization, with the architectural patterns, operational practices, and mental models AWS teams use to raise their security bar.

Between sessions, stop by the Security Lounge in the Convention Lounge at the Wynn to recharge, meet other security practitioners, and visit kiosks from select AWS security partners.

Security sessions all week

You don’t have to wait for Thursday. Security sessions run every day, with 12 on Monday, 16 on Tuesday, 9 on Wednesday, and 3 on Friday, not counting repeats. Monday and Friday sessions are all at the Wynn. Tuesday and Wednesday sessions are spread across the Wynn, MGM Grand, and Caesars Palace, so check the venue when you build your agenda.

Sessions for every security domain

Whatever part of security you work in, the catalog has sessions for it. Here are a few to start with in each domain, and the full list can be found in the session catalog.

Application security and AWS Continuum

AWS Continuum runs through the application security sessions this year.

  1. SEC427 is a Monday 12:00 PM code talk that threat models an agentic development workflow from user story to deployment with AWS Continuum.
  2. SEC312 is a Tuesday 3:30 PM workshop where you run an on-demand penetration test against a live application with AWS Continuum.
  3. SEC311 is a Thursday 1:00 PM builders’ session that wires AWS frontier agents into an automated find-and-fix security loop.
  4. SEC384 is a Thursday 2:30 PM breakout on how AWS Continuum discovers, validates, and fixes code vulnerabilities in one workflow. SEC304 and SEC426 go deeper on AWS Continuum on Tuesday and Thursday.

Threat detection and incident response

  1. SEC323 is a Tuesday 3:30 PM workshop where you recover from a simulated ransomware event and prove the restore is clean.
  2. SEC405 is a Thursday 12:00 PM builders’ session that takes a vulnerable application from discovery to fix with Amazon Inspector, AWS Continuum, and Amazon GuardDuty.
  3. SEC501 is a Thursday 1:00 PM breakout that goes inside the research behind the GuardDuty detection engine.
  4. SEC390 is a Thursday 4:00 PM breakout on how Woodside handed SOC monitoring to AWS Security Incident Response to focus on threat hunting.

Identity and access management

  1. SEC388 is a Monday 10:00 AM breakout where the National Institutes of Health shares how it manages identity lifecycle across clouds.
  2. SEC424 is a Tuesday 2:30 PM chalk talk on how IAM evaluates your policies on every request.
  3. SEC362 is a Thursday 8:00 AM workshop where you build authentication, authorization, and audit for AI agents.
  4. SEC419 is a Thursday 11:30 AM chalk talk on OAuth delegation patterns for agents with Amazon Bedrock AgentCore Identity.

Cloud governance

  1. SEC302 is a Monday 10:00 AM breakout on building a governance foundation for AI workloads that grows with autonomous agents.
  2. SEC349 is a Thursday 8:30 AM workshop where you build a layered controls stack for a fleet of agents.
  3. SEC374 is a Thursday 1:30 PM breakout on how Moeve turned natural language into enforced governance controls.
  4. SEC351 is a Friday 9:00 AM breakout on running governance across AWS and other clouds as one operation.

Network and application protection

  1. SEC364 is a Tuesday 1:00 PM breakout on how Coupang secures its software and AI supply chains with AWS Network Firewall.
  2. SEC303 is a Wednesday 10:00 AM breakout on the network security capabilities AWS built for agentic workloads.
  3. SEC363 is a Thursday 12:00 PM breakout on what’s new in Amazon Route 53 Resolver DNS Firewall.
  4. SEC313 is a Thursday 2:30 PM builders’ session where you set up the AWS Network Firewall proxy for secure egress.

Data protection

  1. SEC206 is a Thursday 1:00 PM breakout on meeting digital sovereignty requirements with the AWS European Sovereign Cloud.
  2. SEC207 is a Thursday 2:30 PM lightning talk where Capital One explains how it runs payment cryptography in the cloud.
  3. SEC316 is a Thursday 4:00 PM builders’ session where teams race through post-quantum migration challenges.
  4. SEC204 is a Friday 11:30 AM breakout where AWS and DXC Technology share how to prepare for post-quantum cryptography at scale.

AI security

  1. SEC328 is a Tuesday 11:30 AM chalk talk on enforcing AI guardrails across your organization without slowing teams down.
  2. SEC237 is a Thursday 8:30 AM breakout on how AWS foundational security extends into AI services.
  3. SEC343 is a Thursday 12:00 PM builders’ session where you watch an MCP tool poisoning attack and build the defenses against it.
  4. SEC341 is a Thursday 3:00 PM workshop where you layer defenses for an AI agent from the prompt to tool execution.

Culture of security

Three sessions focus on how security teams work in the agentic era.

  1. SEC425 is a Wednesday 9:00 AM breakout on how AWS uses automated reasoning and neurosymbolic AI to prove security properties.
  2. SEC342 is a Thursday 11:30 AM breakout on the lessons the AWS Office of the CISO learned from Project Glasswing.
  3. SEC350 is a Thursday 4:00 PM chalk talk on building trust between people when agents work on your behalf.

Session types

Sessions come in several formats, and most security sessions sit under the Security, Identity, and Compliance (SEC) topic in the event catalog. If you attend in person, lightning talks are walk-up only. For every other format, you can reserve a seat in the event portal (login required) or join as a walk-up based on availability.

Format What to expect
Breakout sessions 60-minute presentations led by AWS security experts and customers
Chalk talks 60-minute interactive sessions where AWS experts whiteboard and take your questions
Code talks 60-minute sessions built around live coding and technical implementation
Builders’ sessions 60-minute small-group sessions where you build alongside an AWS expert
Workshops 120-minute hands-on sessions where you work directly with AWS services
Lightning talks 20-minute talks on a single focused topic

Security, Identity, and Governance track sessions

You can find all of the Security, Identity, and Governance track sessions listed on the agenda page. Dates and venues can change, so check the event portal for the latest details.

Beyond the sessions

Security kiosks in the AWS Village

If you’d like to speak to AWS experts on something you’re working on, or find out the ins and outs of a specific AWS security service, find the security kiosks in the AWS Village in the Expo. Here you can talk with AWS experts about identity and access management, threat detection and response, governance and compliance, application security, and network security. The Expo opens Monday, November 30 at 4:00 PM and runs daily through Thursday, December 3.

Security meetups

Join a security meetup on Tuesday, Wednesday, or Thursday, most of them at the Wynn. Meetups are small-group conversations with AWS experts, with no slides, on topics such as detection and response at machine speed, data protection and the post-quantum shift, and identity for humans, workloads, and AI agents.

Receptions

There are several Security, Identity & Governance receptions over the course of the week so be sure to speak with you AWS account manager and ask for the details. Most of these events require pre-registration so don’t wait!

First time at re:Invent?

For those of you that have never attended a re:Invent before, these four tips will help.

  1. Pick up your badge on Sunday if you can, since badge pickup opens before the first sessions.
  2. Download the AWS Events mobile app to build your agenda.
  3. While the vast majority of Security sessions are located at the Wynn, plan your route between venues, since walking between hotels on the Strip takes longer than it looks.
  4. On Thursday, plan to spend your day at the Wynn, where every security session that day takes place.

See you in Las Vegas

Start building your security agenda today in the re:Invent security catalog. Recordings of many breakout sessions will be posted on the AWS Events YouTube channel after the event.

See you in Las Vegas.

If you have questions about this post, contact AWS Support or start a new thread on AWS re:Post.


Brandon Carroll

Brandon Carroll

Brandon is a Senior Technical Product Marketing Manager at AWS, where he leads go-to-market for network security services including AWS Network Firewall. He holds CCIE Security #23837 and wrote Securing the AWS Cloud (Wiley, 2025), one of six books he has authored on networking and security.

How Twilio modernized billing at 70% lower cost with Amazon Redshift

Post Syndicated from Sean McKibben original https://aws.amazon.com/blogs/big-data/how-twilio-modernized-billing-at-70-lower-cost-with-amazon-redshift/

This post is co-written with Sean McKibben from Twilio.

This post describes how Twilio’s Commerce Platform team modernized their billing pipeline by migrating from a legacy MySQL system to a modern data architecture on AWS. The new billing platform is built on Amazon Redshift Serverless, with streaming ingestion using Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Zero-ETL integration with Amazon Aurora MySQL.

“Our billing transformation with Amazon Redshift empowered the business to deliver new ways of selling which were impossible to consider before. The fact that it did this while simultaneously reducing costs by 70% and reducing operational overhead told us how powerful the approach was.”

— Sean McKibben, Principal Software Engineer, Twilio

Twilio is a cloud communications platform with APIs for messaging, voice, email, and video. It serves over 400,000 active customer accounts and more than 12 million developers worldwide to build unique, personalized experiences for their customers. Twilio’s Commerce Platform business unit owns shopping, metering, and rating domains, processing tens of billions of usage events per month across 200 million price points. The platform supports Twilio’s Opportunity-to-Revenue (OTR) initiative, a company-wide program to modernize the full billing lifecycle from customer intake through invoicing.

Challenges with the legacy billing system

Twilio built its billing system on Amazon Aurora MySQL, which reliably powered 70 partitioned database instances and converted billions of events into invoices across messaging, voice, email, and video. As Twilio’s business grew and data volumes expanded significantly, the team recognized an opportunity to evolve the architecture to meet new demands.

Following are the primary challenges with the legacy platform:

  • Processing slowdowns, with backlogs sometimes taking hours to clear.
  • Operational fragility because of frequent ETL failures requiring engineers to spend more time troubleshooting pipelines than delivering new features.
  • Higher infrastructure costs that were disproportionate to the business value delivered. It also lacked the flexibility to smoothly deliver features like backdated changes to pricing models or complex organizational lifecycles without manual intervention.

The billing system needs to generate invoice line items with financial-grade consistency. There can be no duplicate charges or missing events. The existing system could not support new pricing models without re-architecting, and the finance team could not run analytical queries without impacting production.

Twilio needed a distributed data warehouse architecture that could handle both transactional billing integrity and analytical flexibility. The architecture had to process billing calculations in minutes rather than hours and let finance and product teams query data without impacting production.

Overview of the solution

Twilio’s Commerce Platform team evaluated several approaches, including traditional data warehouses, data lakes with query engines, and split architectures with separate operational and analytical systems. Traditional data warehouses are optimized for analytics at the expense of real-time data consistency while operational databases handle transactional workloads but struggle with complex analytical queries at scale.

With Amazon Redshift, Twilio bridged that gap, helping queries return consistent results even for concurrent write workloads, while still maintaining high analytical performance. The key capabilities that drove Twilio to adopt Amazon Redshift Serverless are as follows:

  • Serverless operations — Amazon Redshift Serverless eliminates provisioning, capacity planning, and failover management. Compute scales automatically in response to workload demand, optimizing cost without manual intervention.
  • Real-time streaming ingestion — Billing events stream continuously through Amazon MSK. Amazon Redshift streaming ingestion delivers near real-time event data directly into the data warehouse with no requirement of intermediate landing zones.
  • Transactional integrity — Using serializable isolation with Amazon Redshift helped deliver consistent query results across concurrent workloads, thereby preventing data anomalies that would require custom reconciliation logic.
  • Materialized views AUTO refresh — Materialized views (MV) with AUTO refresh incrementally aggregate billing events by customer, product, and day, delivering near real-time rated data to downstream workgroups without batch processing.
  • Zero-ETL integration — Amazon Aurora zero-ETL integration with Amazon Redshift with history mode enabled automatically replicates full change history from Amazon Aurora MySQL databases into Amazon Redshift with no custom change data capture (CDC) pipelines required.
  • Distributed data warehouse — With Amazon Redshift data sharing, multiple workgroups securely share data across workloads. This provides workload isolation by running analytical queries on an independent consumer workgroup without slowing down invoice processing, along with cost visibility per workload.
  • Integration with existing data lake — Amazon Redshift unload to Amazon Simple Storage Service (Amazon S3) and direct writes to Amazon S3 Iceberg tables indexed with AWS Glue Data Catalog eliminated Spark ETL jobs for data lake delivery, allowing broader organizational access to the data.
  • Transformation orchestration with dbt — dbt (data build tool) is used for orchestrating Amazon Redshift MV refreshes and stored procedure execution, managing the dependency graph across more than 200 million price points with auto-generated documentation and full calculation lineage. Amazon Redshift full SQL compatibility with dbt Core allows them to define metering, rating, and bookkeeping logic as reproducible SQL directed acyclic graphs (DAGs).

The following diagram illustrates the architecture of the solution implemented by Twilio:

Twilio billing architecture: Amazon MSK streaming and Amazon Aurora Zero-ETL into Amazon Redshift Serverless workgroups feeding Amazon S3, DynamoDB, and Amazon Athena

Figure 1: End-to-end solution architecture

The key implementation steps for the architecture are as follows:

1. Ingestion layer

Twilio’s billing events originate from product teams across messaging, voice, email, and video. The data from these source systems are ingested into the billing system using the following ingestion pipelines:

Streaming ingestion

Each product emits usage events to Amazon MSK topics within their Amazon MSK Serverless clusters. Billing events from these topics flow into Amazon Redshift using streaming ingestion. AUTO refresh option for Amazon Redshift MVs provides real-time aggregation as events land, incrementally aggregated by customer, product, and date, thereby processing billions of events daily.

Serializable transaction isolation, combined with deduplication logic in the materialized views, allows each event to be counted exactly once.

Zero-ETL integration

Twilio’s product catalog and pricing configuration data live across multiple Amazon Aurora MySQL clusters. This legacy system contains customer account data, pricing configurations, and historical billing records that must be accessible to the new engine for reconciliation. The legacy system priced everything with whatever configuration was current at the time of processing, which worked well for forward-looking billing. However, the team needed the flexibility to reprice historical usage for corrections, promotional adjustments, and contract changes.

Using Zero-ETL with history mode for integrating Amazon Aurora databases with Amazon Redshift, every price update and configuration change is automatically captured with timestamps. As a result, the team can reconstruct any bill from any point in time after history mode was enabled. They can also reprice historical usage with the exact configuration that should have applied, or model what invoices would look like under different scenarios.

Additionally, Zero-ETL replicates data from the legacy MySQL billing shards into Amazon Redshift Serverless with CDC, eliminating custom extraction pipelines. This allowed:

  1. Usage and pricing comparison between the new engine and legacy system, required for Sarbanes-Oxley (SOX) compliance.
  2. Billing accuracy validation during the parallel-run period.
  3. A unified query layer across all shards without managing shard-aware queries.

COPY command to load from Amazon S3

Finalized invoice data is exported from the invoicing platform, Zuora, in Apache Parquet format to Amazon S3, providing completed invoice line items, customer charges, and billing summaries that need to be available for customer self-service and console experiences. This invoice data in Amazon S3 is loaded into Amazon Redshift tables using COPY from Parquet on Amazon S3.

2. Transformation layer

The billing transformation logic runs on open source dbt Core with SQL DAGs defining the following transformation pipelines:

Metering

Metering deduplicates raw billing events using transaction identifiers and then aggregates events by customer, product, and time period. It also handles edge cases like late-arriving events and event corrections. dbt Core orchestrates the ingestion while auto-maintained incrementally refreshed Materialized Views aggregate billing events.

Rating

Rating applies pricing rules to metered aggregates. It manages over 200 million price points across multi-tiered volume discounts, promotional discounts that stack in specific orders, multi-product bundles, and bifurcated taxes. Each pricing rule is a discrete SQL model, and dbt orchestrates the dependency graph between them.

Bookkeeping

dbt Core orchestrates SQL transformation DAGs that generate priced aggregate artifacts formatted as invoice line items for the invoicing platform. The Bookkeeper system also creates read-only Iceberg tables from rating system data shares for data lake delivery. dbt cleans and transforms invoice data returned from the invoicing platform through Amazon S3 in Parquet format before it is written to Amazon DynamoDB for customer console experiences.

3. Storage layer

The billing engine uses multiple Amazon Redshift Serverless workgroups with AI-driven scaling, primarily 128 Redshift Processing Units (RPUs) base, up to 1,024 for heavy workloads. Amazon Redshift data sharing distributes rated data across workgroups without ETL or data copies, across all consumers in real time.

As part of the billing pipeline, three Amazon Redshift Serverless workgroups serve distinct workloads:

Metering workgroup

The Amazon Redshift Serverless workgroup hosts the auto-refreshing MVs that deduplicate and aggregate billing events and stores over half a trillion events available for immediate querying. It writes curated financial datasets directly to Amazon S3 as Iceberg tables, indexed with AWS Glue Data Catalog.

Rating workgroup

This Amazon Redshift Serverless workgroup processes pricing configuration information, from aggregated Zero-ETL sources. It then applies pricing to usage aggregates to create the central system of record for rated usage. These core datasets are then shared with Bookkeeper for use-case-specific delivery.

Bookkeeper workgroup (invoice generation)

The Amazon Redshift Serverless workgroup for invoice generation receives rated data through data shares from the rating workgroup. Data shares from this workgroup are also used to feed the Customer Usage API workgroup. This also stores priced aggregate artifacts formatted as invoice line items for the invoicing platform. It processes the invoicing platform’s return data to Amazon S3 and writes to Amazon DynamoDB for customer console experiences.

In addition, the following Amazon Redshift Serverless workgroup serves Twilio’s end customers through their public APIs:

Customer Usage API workgroup

This dedicated Amazon Redshift Serverless workgroup receives rated usage data and product catalog configurations through stored procedures from the source systems and metered aggregates through data shares from the bookkeeper workgroup. It serves near real-time billing queries for the customer-facing usage API without impacting the billing pipeline’s compute resources.

4. Consumption layer

Processed billing data serves five downstream consumers:

  1. Invoicing platform — The Bookkeeper workgroup delivers priced aggregates as invoice line items for customer billing.
  2. Twilio Public APIs — The Customer Usage API workgroup powers near real-time billing queries for customers, backed by live data shares from the Metering workgroup.
  3. One Admin — Internal billing operations dashboards served directly from Amazon Redshift with sub-minute response times.
  4. One Console — Customer self-service experiences, for example balance inquiries, CSV invoice downloads, and so on, are served from Amazon DynamoDB. The Bookkeeper workgroup loads finalized invoice data returned from the invoicing platform to DynamoDB for low-latency API serving end-users.
  5. Product Teams — Amazon Athena queries curated financial datasets on Iceberg tables through the AWS Glue Data Catalog, providing broader organizational access without direct Amazon Redshift access.

Results

Twilio’s modernized billing engine cut infrastructure costs by 70% while accelerating billing recalculations by 12x, all while processing billions of events a month. Twilio launched the new billing system in production in mid-2026, providing rated usage for real customer invoices through Zuora. This new engine modernized on Amazon Redshift Serverless delivered measurable improvements across every dimension, which include:

  1. 70% lower infrastructure cost — Ongoing costs for the billing system dropped by 70%, while the system scaled to store almost two trillion events that the legacy architecture could not accommodate.
  2. 12x faster billing recalculation — Full month recalculations lowered from over 6 hours down to 30 minutes, along with retroactive pricing changes and scenario modeling that were previously impractical.
  3. Over 80% reduction in processing time — 80-85% operational gain across the pipeline, with the team meeting business service level agreements (SLAs).
  4. Sub-minute financial reporting — Finance dashboards moved from daily batch refreshes to sub-minute response times, providing near real-time visibility into billing data.
  5. Complete pricing flexibility — The rating engine now manages Twilio’s complete catalog of 200 million price points, up from a constrained subset, with no duplicate charges or missed events.
  6. Leaner operation — A small team manages what previously required a much larger operations team.

Most significantly, engineers shifted from firefighting pipeline failures to building new product capabilities, a cultural transformation driven by reliability and simplicity of the serverless architecture.

Conclusion

In this post, we showed how Twilio modernized their legacy billing system by adopting Amazon Redshift Serverless as the foundation for a financial-grade, real-time billing system at scale.

The modernized architecture is driven by streaming ingestion using Amazon MSK along with Amazon Redshift Zero-ETL from Amazon Aurora MySQL. With direct writes to Amazon S3 Iceberg tables cataloged with AWS Glue Data Catalog and dbt-driven transformations, Twilio built a billing engine that scales with their business. The new solution helped engineering teams to focus on billing product innovation rather than infrastructure operations. Learn more about how Amazon Redshift helped Twilio redesign their billing engine from their talk at AWS re:Invent 2025, where they co-presented with the Amazon Redshift and Amazon Athena service teams.

To learn more about the AWS services used to build modern data solutions on AWS, refer to the AWS public documentation and stay up to date through the AWS Big Data Blog.


About the authors

Sean McKibben

Sean McKibben

Sean is a Principal Software Engineer at Twilio, where he leads the Commerce Platform Billing Engine. He architected the migration from legacy MySQL-based billing to Amazon Redshift Serverless and has spoken about this work at AWS re:Invent 2025.

Parth Shah

Parth Shah

Parth is a Senior Solutions Architect at AWS, supporting strategic customers in architecting their data and AI workloads. He partners with enterprise engineering teams to design scalable architectures spanning real-time data pipelines, agentic AI frameworks, and multi-region platforms.

Sushmita Barthakur

Sushmita Barthakur

Sushmita is a Senior Data Solutions Architect at AWS, supporting Strategic customers in architecting their data workloads on AWS. With a background in data analytics, she has extensive experience helping customers architect and build enterprise data lakes, ETL workloads, data warehouses and data analytics solutions, both on-premises and the cloud.

Understanding and optimizing materialized views in Amazon Redshift

Post Syndicated from Nick Barclay original https://aws.amazon.com/blogs/big-data/understanding-and-optimizing-materialized-views-in-amazon-redshift/

Analytical queries often repeat the same expensive joins and aggregations, and materialized views (MVs) in Amazon Redshift optimize that pattern. An MV pre-computes and stores a query’s result, so the expensive work happens at refresh time instead of on every read. A query that would otherwise scan and aggregate large tables becomes a fast lookup of the stored result.

That speed has a running cost. Every MV consumes storage, and every refresh consumes compute, whether or not a query ever reads the result. A well-used MV repays that cost many times over. An MV that refreshes constantly but is not read costs more than it saves. So does one that fully recomputes a hundred million rows to serve a handful of queries.

As MVs become more popular in your organization, it can be challenging to keep track of which MVs are worth the maintenance costs. This post introduces a diagnostic view, v_mv_health, that reports each MV’s refresh eligibility, staleness, refresh cost, dependencies, and query activity. A companion stored procedure, sp_populate_mv_definitions(), creates and fills a table, mv_definitions, holding the one signal a view cannot compute. It reads each MV’s definition and flags the SQL constructs that block incremental refresh. Join the two for a single result set that covers these signals. Once deployed, the view and procedure give you the data to make MV health part of your regular operational review.

Solution overview

The following diagram shows how the two components fit together.

Diagram of the v_mv_health view and sp_populate_mv_definitions procedure reading Amazon Redshift system views and joining into the MV health dataset

Figure 1: How the v_mv_health view and sp_populate_mv_definitions procedure combine into the MV health dataset

Both components read from Amazon Redshift system views. The v_mv_health view reads them directly each time you query it. The sp_populate_mv_definitions() procedure reads each MV’s definition, flags constructs that block incremental refresh, and writes the results to the mv_definitions table each time it runs. Joining v_mv_health with mv_definitions produces the MV health dataset, a single result set with one row per MV.

Prerequisites

The diagnostic view and procedure require:

  • An Amazon Redshift provisioned cluster or an Amazon Redshift Serverless workgroup with one or more MVs.
  • sys:superuser role, or the sys:monitor role, so the view can read activity in the cluster or workgroup. Without it, the refresh and query activity the view reports covers only your own sessions. Grant it with GRANT ROLE sys:monitor TO <username>; (for an IAM identity, use the IAMR:role-name form). For the full list of system-defined roles, refer to Amazon Redshift system-defined roles.
  • For a non-superuser (such as a sys:monitor user), USAGE on each schema that contains MVs, because SVV_MV_INFO only returns MVs in schemas the user can access. Grant it with GRANT USAGE ON SCHEMA <schema> TO <username>;.

The diagnostic view

Amazon Redshift already exposes the signals, but each lives in a different system view:

The v_mv_health view joins them into a single row per MV: state, staleness, autorefresh interval, refresh cost, query activity, dependency depth, and whether parent MVs in a chain are stale. The definition for the v_mv_health view is available in the amazon-redshift-utils GitHub repository.

The stored procedure

One signal the view can’t provide is the MV’s definition text. The sp_populate_mv_definitions() procedure iterates through each MV and extracts its definition into the mv_definitions table, created automatically if it doesn’t exist. It then scans each definition for SQL constructs covered in Refresh eligibility. The definition for the sp_populate_mv_definitions() procedure is available in the amazon-redshift-udfs GitHub repository.

The procedure uses a two-phase approach: it stages the MV object IDs into a temporary table first, then walks that local table one row at a time. It executes the pg_get_viewdef() function, which operates on one view at a time. Results are collected in a second temporary table and then replace the contents of mv_definitions in a single transaction, so each run reflects the current state of your MVs. Amazon Redshift drops the temporary tables automatically at the end of the session, so no manual cleanup is needed.

Run the procedure, then join the v_mv_health view to the mv_definitions table it populated:

CALL sp_populate_mv_definitions();

SELECT
    v.*,
    d.incremental_blocker_hint
FROM v_mv_health v
LEFT JOIN mv_definitions d
ON v.mv_schema = d.mv_schema
AND v.mv_name = d.mv_name;

Both objects use the same SQL on provisioned clusters and serverless workgroups. They report the MVs in their own database, so create them in each database that contains MVs.

Note: The view uses a 7-day lookback window because SYS_MV_REFRESH_HISTORY, SYS_QUERY_DETAIL, and SYS_QUERY_HISTORY retain 7 days of data by default. Amazon Redshift can retain system table data beyond 7 days by automatically replicating it to Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3). Long-term retention supports SYS_QUERY_HISTORY and SYS_QUERY_DETAIL, so you can extend the query-activity signals by pointing the view’s queries on them at the retained tables. At the time of writing, SYS_MV_REFRESH_HISTORY is not among the retained system tables, so the refresh-cost columns remain limited to the 7-day in-cluster window unless you capture that history yourself.

What the output tells you

The joined output returns one row per MV:

Column What it means
mv_database Database containing the MV
mv_schema Schema containing the MV
mv_name MV name
state 1 (incremental), 0 (full_recompute), 101-105 (broken). Refer to SVV_MV_INFO
state_label incremental, full_recompute, or broken with its cause (for example, broken:column_renamed)
is_stale Whether MV data is out of date relative to base tables; NULL for MVs on external tables other than Iceberg.
is_autorefresh Whether automatic refresh is turned on
autorefresh_interval_sec Autorefresh interval in seconds; NULL when autorefresh is off
is_default_autorefresh_interval Whether the MV uses the cluster or workgroup default interval rather than its own. false when autorefresh is off
is_autorewrite_eligible Whether the optimizer can transparently rewrite queries to use this MV
refresh_count Refresh attempts in the last 7 days, including failed refreshes and refreshes that found the MV already up to date
query_count Queries that read the MV in the last 7 days, including queries served through automatic query rewriting. Refreshes are excluded; NULL if the MV’s storage table can’t be found in the catalog
recompute_to_query_ratio Full-recompute refreshes (not incremental) ÷ queries. High values indicate refresh cost may exceed benefit; NULL when query_count is 0 or NULL
avg_refresh_sec Average refresh duration in seconds
last_refresh_status Status message from the most recent refresh, such as incremental, full recompute, or already up to date
mv_rows Row count of the MV, for gauging refresh cost against usage
chain_depth Depth in a dependency chain (0 = no MV dependencies)
mv_dependencies Parent MVs the MV depends on; NULL if it has no parent MVs
stale_ancestors Parent MVs in the chain that are currently stale; NULL if no parent MV is stale
pct_of_total_query_time Refresh time as a percentage of total query time on the cluster or workgroup
incremental_blocker_hint SQL constructs preventing incremental refresh, evaluated only for state 0 MVs (none otherwise, unidentified when no known construct matches). From mv_definitions

Refresh eligibility

Amazon Redshift refreshes an MV in one of two ways. In an incremental refresh, Amazon Redshift identifies the changes to the data in the base tables since the last refresh and updates the data in the MV. In a full recompute, it reruns the MV definition, replacing the data in the MV. Amazon Redshift automatically chooses the method based on the query that defines the MV.

Each MV in Amazon Redshift falls into one of three states:

  • Full recompute (state 0): The entire MV is rebuilt from scratch on every refresh.
  • Incremental (state 1): Only changed rows are processed on refresh.
  • Broken (state 101-105): The MV cannot refresh at all and must be dropped and recreated.

The state column tells you which category each MV falls into. An MV’s state depends on its definition, not its size. Its size (mv_rows) determines how much that state costs. An incremental refresh on a 100-million-row table might process 50 changed rows, while a full recompute scans all 100 million regardless of how few changed.

Note: A state 1 MV can still occasionally fully recompute, for example after a VACUUM with the FORCE option on a base table while the MV is out of date, or when the MV hasn’t been refreshed for an extended period. These show up as full recomputes in recompute_to_query_ratio even though the state is 1. If you need VACUUM FORCE, run it straight after refreshing the dependent MVs.

Certain SQL constructs block incremental refresh. The incremental_blocker_hint column identifies which constructs are preventing incremental eligibility. If any of the following appear in the MV definition, the MV cannot refresh incrementally and falls back to a full recompute on every refresh:

  • Distinct: SELECT DISTINCT, COUNT(DISTINCT ...).
  • Outer joins: LEFT, RIGHT, or FULL OUTER JOIN.
  • Window functions: anything with an OVER() clause (ROW_NUMBER, RANK, SUM, NTILE, and so on).
  • Subqueries: in the WHERE clause or SELECT list (subqueries in the FROM clause are fine).
  • Mutable functions: GETDATE(), SYSDATE, RANDOM(), CURRENT_DATE.
  • Set operations: UNION, INTERSECT, EXCEPT, MINUS.
  • Ordered and holistic aggregates: MEDIAN, PERCENTILE_CONT, PERCENTILE_DISC, LISTAGG, APPROXIMATE COUNT, APPROXIMATE PERCENTILE.

An MV may trip more than one of these at once, and incremental_blocker_hint lists each one it finds.

Note: incremental_blocker_hint is a heuristic text scan of the MV definition, not a semantic parse, and is evaluated only for MVs in state 0. The other MVs show none. It matches whole-word SQL keywords, so it won’t trip on names like distinct_count, but a keyword inside a string literal (for example, WHERE status = 'union') can still produce a false positive. Treat it as guidance and verify by inspecting the definition.
OUTER JOIN is a frequent blocker. Outer joins (FULL, LEFT, and RIGHT) are a legitimate and important SQL pattern, but they prevent incremental refresh in MVs. If you need incremental eligibility, you have options: if the join always produces a match (no NULLs in the result), rewriting as INNER JOIN restores incremental refresh with no change to output. If the outer join is genuinely needed, consider handling the unmatched rows upstream. For example, pre-joining in an ETL step, or using a regular view for the outer join while keeping the MV incremental on the inner-joined subset.

For the full list of incremental refresh limitations, refer to Refreshing a materialized view in the Amazon Redshift documentation.
Refresh cost

Every refresh consumes compute resources. The pct_of_total_query_time column shows what share of total query time is spent refreshing each MV, and avg_refresh_sec identifies individual MVs with unusually long refresh times. There is no universal threshold, because what counts as expensive depends on the cluster. Start with the MVs that rank highest on pct_of_total_query_time: those in the highest decile of refresh cost, and those whose cost looks large relative to the queries they serve.

The net-negative MV. An MV that refreshes frequently but is never queried consumes resources without delivering value: refresh_count > 0 with query_count = 0. If is_autorefresh = true and query_count = 0, consider dropping the MV. If it’s still needed occasionally, lengthen its autorefresh interval or switch it to manual refresh on demand.

Refresh-to-query ratio. Even when queried, the refresh cost may exceed the benefit. If an MV fully recomputes many times for every query that reads it, the caching isn’t paying for itself. The recompute_to_query_ratio column flags this. Consider lengthening the autorefresh interval or scheduling refreshes to match how often the MV is read, or dropping the MV entirely.

Note: Amazon Redshift supports creating an MV on a consumer warehouse over data-shared base tables or directly refreshing an MV from a remote warehouse. This isolates the compute and minimizes cluster disruption, whether the refresh is full or incremental.

Dependencies and staleness

Amazon Redshift supports MVs that reference other MVs, known as nested MVs. Nested MVs can be refreshed together, in dependency order, using REFRESH ... CASCADE (refer to Harnessing the power of nested materialized views and exploring cascading refresh). The chain_depth column shows how deep each MV sits in a dependency tree, and mv_dependencies lists its parent MVs.

Staleness propagates one hop at a time. The is_stale column reports whether an MV’s data is behind its base tables. When base table data changes, the immediate dependent MV is marked is_stale = true. Downstream MVs remain is_stale = false until their direct parent is refreshed. At that point they become stale in turn. For deeper chains, is_stale = false on a downstream MV indicates freshness relative to its immediate parent, not the original base table. The stale_ancestors column walks the full chain and reports which parent MVs are currently stale.

CASCADE refresh solves propagation but requires explicit invocation. REFRESH MATERIALIZED VIEW mv_name CASCADE refreshes the entire chain in topological order (parent MVs first). It is not automatic and autorefresh does not cascade, so run it at your required freshness interval, for example on a schedule with Amazon EventBridge and the Amazon Redshift Data API, or as the final step of the ETL job that loads the base tables. Refer to the Autorefresh section for details on when AUTO REFRESH YES is supported.
Note: CASCADE is supported only for chains built on local tables, data-shared tables, local MVs, and streaming MVs. It doesn’t extend to MVs on Amazon Redshift Spectrum sources or to MVs shared from another warehouse, which must be refreshed individually in dependency order. Each additional level in a dependency chain adds refresh latency and widens the window where downstream MVs serve data that hasn’t caught up. Keep chains shallow, and weigh that lag against the benefit the chain provides.

Refreshing materialized views on external tables

MVs can cache results from external tables stored in Amazon S3, so each query reads the stored result instead of re-scanning the same Amazon S3 files. Refresh behavior depends on two factors:

  1. Data storage format: a standard file type (Parquet, CSV, Avro) or an open table format (Apache Iceberg, Hudi, Delta Lake). When new files appear in Amazon S3, MVs on standard file types and Iceberg refresh incrementally, whether or not they aggregate. Hudi and Delta Lake don’t support incremental refresh.
  2. Aggregation: whether the MV aggregates (GROUP BY, SUM, COUNT). When a file is deleted or overwritten, a non-aggregating MV stays incremental, but an aggregating MV must fully recompute, because aggregates can’t be undone without re-reading the remaining data. The last_refresh_status column reports this as “A full recompute was successfully completed as a data file was deleted.”

Apache Iceberg supports incremental refresh in more cases than the other formats. Iceberg’s metadata layer tracks row-level changes (inserts, deletes, updates, compaction), so aggregating MVs stay incremental even when rows are removed. Iceberg is the only data lake format that accepts AUTO REFRESH YES. For MVs over data lake sources where incremental refresh matters, Iceberg is the strongest fit (refer to materialized views on external data lake tables). For a deeper treatment of how incremental refresh works across data lake table formats, refer to Incremental refresh for Amazon Redshift materialized views on data lake tables.

Note: An incrementally refreshable materialized view on Iceberg tables may fall back to a full recompute if that is expected to perform better, or if it joins multiple base tables and more than one of them has been updated since the last refresh.

The following table summarizes the refresh method each source format uses for file additions and deletions, and whether it supports autorefresh:

Source format On file addition On file deletion, non-aggregating MV On file deletion, aggregating MV Autorefresh
Apache Iceberg Incremental Incremental Incremental Supported
Parquet / CSV / Avro Incremental Incremental Full recompute Not supported
Hudi / Delta Lake Full recompute Full recompute Full recompute Not supported

Note: On Iceberg tables, an aggregating MV falls back to a full recompute if a snapshot it needs has been expired. Expire snapshots only after refreshing the MVs that depend on the table, and if you use AWS Glue Data Catalog snapshot retention, keep the retention period longer than the interval between MV refreshes. Refresh after compaction stays incremental but processes more data, so plan for a longer refresh.

On Amazon Redshift RG instances and Serverless, external table queries run through an integrated query engine rather than Amazon Redshift Spectrum, which can reduce MV refresh times on Iceberg data. No configuration change is required.

Autorefresh

Autorefresh keeps MVs current without manual scheduling. The is_autorefresh column shows which MVs have it turned on, and autorefresh_interval_sec shows how often Amazon Redshift checks each one for staleness. An autorefresh runs only when the MV is stale, with the same priority as other user queries. On provisioned clusters, autorefresh queries run in your workload management (WLM) queues alongside your workload and appear in STL_QUERY. On Amazon Redshift Serverless, they consume Redshift Processing Units (RPUs) like any other query. On both, SYS_MV_REFRESH_HISTORY is where you see autorefresh activity, because it doesn’t appear in SYS_QUERY_HISTORY.

Autorefresh on high-churn tables generates constant refresh activity. Some base tables change frequently through streaming ingestion, AWS Database Migration Service (AWS DMS) replication, or zero-ETL. On those tables the MV is almost always stale, so autorefresh runs at every interval (5 minutes by default). The refresh_count column quantifies this. The worst case is autorefresh on a state 0 MV. Every refresh is a full recompute, so at the default interval that’s a full rebuild of the MV every 5 minutes. If the MV doesn’t need to be that current, keep autorefresh on but lengthen the interval (minimum 60 seconds) to match how often the results are queried: ALTER MATERIALIZED VIEW mv_name AUTO REFRESH YES INTERVAL <seconds>. To change the default for every MV on the cluster or workgroup, use ALTER SYSTEM SET default_mv_auto_refresh_interval = <seconds>. For details, refer to ALTER MATERIALIZED VIEW and ALTER SYSTEM. Custom intervals aren’t supported on streaming MVs.

Autorefresh does not cascade. It refreshes only the configured MV, not its dependents. AUTO REFRESH YES is rejected at creation time on nested MVs and on external tables other than Iceberg, returning an error rather than being silently ignored. On a nested MV the message is “Auto-refresh is not supported for materialized views defined on other materialized views.” It is supported on local single-level MVs over Iceberg or datashare tables, but not on an MV that combines both.

Broken materialized views

An MV becomes permanently broken when the definition of its base table changes in certain ways. The state column shows values 101-105 for broken MVs, with a label indicating the cause (refer to SVV_MV_INFO for the full state code reference).

Renaming an object that an MV depends on is not blocked, and it leaves the MV unable to refresh. A rename of a column, table, or schema completes without an error and moves the MVs that reference it to a broken state (103-105). Once broken, an MV cannot be refreshed, and renaming the object back does not restore it. The fix is to DROP and CREATE the MV.

Dropping a column that an MV uses, or changing its data type, is rejected. Amazon Redshift returns an error and the MV stays healthy.

Identify affected MVs before you alter a base table or column. SVV_MV_DEPENDENCY only shows MV-on-MV relationships, not base-table dependents. Before you make such a change, use the v_view_table_column_dependency view in the amazon-redshift-utils GitHub repository to identify the dependent MVs and the specific columns they rely on.
Automatic query rewriting

Amazon Redshift can rewrite a query on base tables to read from an MV, even when the query doesn’t name it (refer to Automatic query rewriting to use materialized views). The query_count column includes these reads. The is_autorewrite_eligible column shows whether the MV’s definition allows rewriting.

Eligible doesn’t mean used. Amazon Redshift skips a stale MV until its next refresh, even though the flag stays true. The flag also reads true for nested and broken MVs, which aren’t used. To confirm a specific query was rewritten, run EXPLAIN on it. In a rewritten plan, the base tables the MV covers no longer appear. In their place is a scan of an internal table that holds the MV’s results.

Should this be a materialized view?

Not every cached result benefits from being an MV. The following characteristics indicate when an MV is a strong fit and when an alternative is likely better:

Favors a materialized view Points to an alternative
Analytical queries from dashboards and analysts Application lookups serving thousands of concurrent requests
Multiple users or queries read the result The result is read once or rarely
The query scans a large table but returns few rows The query returns most of the rows it scans
Query latency is unacceptable without pre-computation A regular view already meets the latency requirement
Readers can tolerate data that is a refresh interval old Readers need sub-minute freshness

When your workload matches the right-hand column, a different approach usually fits better: a regular view when the query is already fast enough, in-stream transformation when readers need sub-minute freshness, and an in-memory cache such as Amazon ElastiCache for application lookups at high concurrency.

Putting it together

Deploy the diagnostic view and stored procedure. Run them periodically. Weekly is sufficient for most clusters. Focus on:

  1. State 0 MVs with high refresh cost: Check incremental_blocker_hint. If it names an SQL construct, refactor it (for example, OUTER JOIN to INNER JOIN). If it reads unidentified, confirm the full recompute is justified.
  2. MVs with query_count = 0: Consider dropping them.
  3. Deep chains with stale ancestors: Refresh with REFRESH ... CASCADE to bring the chain current, and flatten chains that are deeper than they need to be.
  4. Broken MVs (state 101-105): Drop and recreate.
  5. Autorefresh MVs on high-churn tables: Compare refresh_count against query_count. When refreshes far outnumber reads, lengthen the autorefresh interval to match how often the results are actually queried.

The goal is MVs whose refresh cost is repaid by the queries they accelerate.

Automate the review. Rather than running the diagnostic by hand, schedule it. v_mv_health is consistently current because it reads the system views each time you query it, so only the procedure needs a schedule. For a basic setup, run CALL sp_populate_mv_definitions(); on a cadence with Amazon EventBridge and the Amazon Redshift Data API. For alerting or dashboards, refer to Building an event-driven application with AWS Lambda and the Amazon Redshift Data API, which uses Amazon EventBridge and AWS Lambda to run a stored procedure on a schedule.

Cleaning up

The diagnostic objects are lightweight (a view, a stored procedure, and a small definitions table), but if you no longer need them, remove them with:

DROP VIEW IF EXISTS v_mv_health;
DROP PROCEDURE sp_populate_mv_definitions();
DROP TABLE IF EXISTS mv_definitions;

Summary

In this post, we showed how to check the health of the MVs in an Amazon Redshift database from a single result set. The v_mv_health view and the sp_populate_mv_definitions() procedure surface the signals that matter. Together they cover refresh eligibility, cost, staleness, dependencies, broken states, and autorefresh behavior. Call the procedure, join its output to the view, and you can see which MVs need attention first.

With v_mv_health and sp_populate_mv_definitions() deployed in each database that contains MVs, you can make MV health a routine part of your operational reviews.

Next steps. The v_mv_health and v_view_table_column_dependency views are available in the amazon-redshift-utils GitHub repository, and the sp_populate_mv_definitions() procedure is available in the amazon-redshift-udfs GitHub repository. To go deeper on the topics this post touched, see Harnessing the power of nested materialized views and exploring cascading refresh and Incremental refresh for Amazon Redshift materialized views on data lake tables.


About the author

Nick Barclay

Nick Barclay

Nick is a Senior Specialist Solutions Architect for Data and AI at AWS, working with public sector customers. He has spent his career building data and analytics solutions across Australia, New Zealand, and the United States, and now helps AWS customers design and optimize their data platforms. When he’s not working, you’ll find him swimming off one of the beaches on Australia’s Gold Coast.

Handling large volume of transactions with AWS Lambda Managed Instances

Post Syndicated from Mythili Annamalai Sekar original https://aws.amazon.com/blogs/compute/handling-large-volume-of-transactions-with-aws-lambda-managed-instances/

Pre-scheduled events like concert ticket on-sales and product launches can drive a load spike 100 times higher than the baseline. The spike persists for a few hours while the inventory clears, then traffic returns to normal. If you miss the first minute of the on-sales, customers experience errors while competitors keep selling, and the event’s reputation takes a hit. Over-provision for the burst, and you pay for peak capacity 24 hours a day, 365 days a year. The actual peak lasts 10 minutes and happens 10 times a year.

In this post, you will see how AWS Lambda Managed Instances, a capability of AWS Lambda, handles predictable traffic bursts. It keeps compute capacity warm before the on-sales event opens and scales it back down afterward. You will see a reference ticketing implementation that sustains 40,000 transactions per second (TPS) for 120 seconds.

Understanding Lambda Managed Instances

Lambda Managed Instances runs your Lambda functions on Amazon Elastic Compute Cloud (EC2) instances in your account, including Graviton4 and memory-optimized instance types. AWS handles the underlying infrastructure lifecycle (provisioning, scaling, patching, and routing), while you benefit from EC2 pricing including Compute Savings Plans and Reserved Instances.

Lambda Managed Instances provides several benefits. With pre-provisioned execution environments (EE), capacity is already warm before traffic arrives, so there are no cold starts when a burst hits. Scaling bounds are configurable with MinExecutionEnvironments and MaxExecutionEnvironments for each function, and each new EE comes online in 1–2 seconds. With multi-concurrent invocations, one EE handles multiple requests at once, which improves utilization for I/O-heavy handlers. You also get EC2 pricing, so Compute Savings Plans and Reserved Instances apply instead of per-request Lambda pricing.

Lambda Managed Instances is well suited for predictable, spike-shaped workloads that need sustained compute capacity during the peak and can scale back down when traffic returns to the baseline.

Predictable burst workloads work best with Lambda Managed Instances

This post focuses on one of the key capabilities of Lambda Managed Instances: absorbing scheduled traffic bursts without provisioning for peak year-round. Some of the use cases where Lambda Managed Instances helps are ticket and event on-sales (concerts, sports, festivals), live streaming and voting events, and scheduled batch and report generation nightly or hourly jobs that consume steady compute during a defined window.

Use case: High-throughput ticket booking with Lambda Managed Instances

To demonstrate Lambda Managed Instances handling predictable traffic bursts, we built a concert ticketing backend. The solution implements the industry-standard queue-plus-hold-and-confirm booking flow, a pattern that ticketing platforms, airlines, and hotels use to prevent overselling during large traffic spikes. It separates user traffic management from the critical database transactions required to lock inventory.

The following diagram presents the detailed architecture of the solution we built.

Architecture of the ticketing solution: API Gateway routes to three Lambda Managed Instances handlers backed by ElastiCache and DynamoDB

Figure 1: Architecture of the concert ticketing solution across two AWS CloudFormation stacks

The solution deploys two AWS CloudFormation stacks in a single AWS Region. In the first stack, Amazon API Gateway routes public HTTPS traffic through three ticketing handlers hosted in Lambda Managed Instances on a shared capacity provider. Amazon ElastiCache Serverless for Valkey holds the atomic queue counter. Amazon DynamoDB holds durable per-seat state across a write-sharded inventory table (500 shards) and a bookings table. WarmThroughput is pre-provisioned to absorb the burst without waiting for adaptive capacity. A separate simulation stack drives synthetic load through a three-tier Lambda fan-out, reproducing the on-sales burst shape at any target TPS.
Public traffic and load-generation traffic take completely separate code paths, so the load generator’s own scaling behavior does not affect measurements on the ticketing stack. Each successful booking traverses three Lambda handlers. Handler queue-position assigns an atomic virtual queue number using an INCR on a single ElastiCache key. Handler inventory-lock places a time-bounded hold on a specific seat through a DynamoDB conditional UpdateItem, moving it from AVAILABLE to HELD with a time to live (TTL) of 180 seconds. Handler booking-confirm executes a single TransactWriteItems call that atomically transitions the seat from HELD to CONFIRMED and writes a durable booking record. Either both writes succeed or neither does.

All three handlers are stateless, because each request they receive is treated as an independent, standalone transaction. The mutable state lives in ElastiCache and DynamoDB, stored with safety features like conditional writes and atomic operations to avoid collisions, race conditions, and overwrites. This is why the multi-concurrent EE model of Lambda Managed Instances can serve thousands of simultaneous invocations per instance safely.

What makes this solution better with Lambda Managed Instances

With Lambda Managed Instances, you keep the same Lambda programming model, one function per handler, and the same deployment story, while Lambda Managed Instances handles the fleet. Raise MinExecutionEnvironments a few minutes before an on-sales opens, let it burst inside the Min to Max range while traffic is live, and scale back down when the window closes.

Deploy the application

For the full deployment instructions, refer to the README file in the GitHub repository after you have cloned it.

Prerequisites

Run the application

Once deployed, all test traffic goes through the simulation API. The sample includes an optional single-page web user interface (UI) (see the demo-ui/ folder in the repository) that wraps the same endpoints and renders the per-burst results interactively.

Read the “Cost considerations” section before running a simulation to understand the cost you will incur in the process.

1. Smoke test – low TPS to verify the pipeline end-to-end:

By default, deploy.sh provisions a cost-safe baseline of three warm EEs (Min=1, Max=3 per handler). The following smoke test works on this baseline.

curl -X POST https://<sim-api>/v1/simulation/start \
-H 'Content-Type: application/json' \
-d '{"run_id": "smoke-1", "target_tps": 50, "ramp_duration_seconds": 10, "sustain_duration_seconds": 60}'

2. Peak-load test

To reproduce the headline result, scale the Lambda handlers to the per-handler Min and Max values before firing the peak-load test. Refer to the Peak-load testing section of the GitHub repository before firing the burst. This also requires an EC2 vCPU and an API Gateway account-throttle quotas increase above the default.

3. View results

curl “https://<sim-api>/v1/dashboard?run_id=onsale-1”

The response includes total requests, total bookings written to DynamoDB, delivered peak TPS, and end-to-end latency percentiles.

Interactive demo UI

The sample repository ships an optional single-page web UI (in the demo-ui/ folder) that wraps the same simulation and dashboard endpoints as the preceding curl examples. Point it at your simulation API endpoint, then fire bursts and view results interactively without leaving the browser.

Configure and start the UI:

# In demo-ui/config.js, set SIMULATION_API_URL to your simulation endpoint.
cd demo-ui && python3 serve.py
# Serving on http://localhost:8000/

Fire a burst. Choose a target load (a preset button or a custom TPS value), set the sustain duration and ramp, then choose Start burst. The UI sends a POST request to /simulation/start and stores the returned run_id and event_id, so you can query DynamoDB directly if you want to drill deeper.

View results. After the burst completes, choose View results. The UI queries API Gateway metrics, DynamoDB, CloudWatch Logs Insights, and CloudWatch Lambda metrics in parallel to reconstruct the run: total requests received, durable bookings written, and a per-handler table showing EEs used, Lambda throttles, and p95/p99 latency.

Demo UI results panel showing 4,804,200 API Gateway requests and 1,750,886 durable bookings with per-handler latency

Figure 2: Demo UI results panel from a 40,000 TPS, 120-second run

The panel shows 4,804,200 API Gateway requests and 1,750,886 durable bookings, plus a per-handler table with the baseline EE pool (50/100/150 for queue-position, inventory-lock, and booking-confirm). During the burst, 36 additional EEs are pre-emptively warmed on booking-confirm, with zero Lambda throttles and p99 latencies of 4.7, 15.8, and 39.8 ms.

The identifiers panel at the top exposes the burst’s run_id (the partition key in the simulation metrics table) and event_id (used in both the inventory and bookings tables), so you can locate them directly in DynamoDB or CloudWatch Logs Insights for the specific burst you ran.

What we measured

Across a load range from 5,000 to 40,000 requests per second, the pre-warmed EE pool served every burst without cold-start impact. Key results from the headline 40,000 TPS × 120-second burst:

Metric Value
Delivered peak throughput 40,035 req/sec
Total HTTP requests 4,804,200
Durable bookings written to Amazon DynamoDB 1,750,886
End-to-end p50 / p99 latency 44 ms / 121 ms
AWS Lambda errors 0
AWS Lambda concurrency throttles 0
Amazon DynamoDB write throttles 0

The tested range spanned 5,000 to 40,000 requests per second, an 8× spread in delivered load. Across it, p99 latency stayed within a 3 ms band. Doubling sustained throughput from 20,000 to 40,000 requests per second held at exactly 121 ms, which confirms that the pre-warmed pool had substantial headroom throughout the tested range.

Observability

Lambda Managed Instances automatically publishes metrics to CloudWatch and structured logs to CloudWatch Logs, giving you visibility into function performance and capacity utilization without additional code. During a burst, the metrics that matter most are:

  • Duration percentiles per handler to confirm p99 latency stays flat as load rises.
  • ConcurrencyThrottles to detect if any handler hits its MaxExecutionEnvironments ceiling.
  • Errors for handler-side failures.
  • EE count (log-derived) to observe how quickly Lambda Managed Instances adds warm capacity above Min.

The sample repository includes a demo dashboard endpoint that queries CloudWatch metrics, CloudWatch Logs Insights, and DynamoDB in parallel to reconstruct a per-burst report, API Gateway request count, durable bookings landed, distinct EEs used, and per-handler latency percentiles. Reconciling the simulation-side counts against the AWS ground truth catches load-generator artifacts and confirms the system-under-test numbers.

Cost considerations

Lambda Managed Instances uses EC2 instance pricing plus a 15% management fee. Compute Savings Plans and Reserved Instances apply to the underlying instance cost.

The Lambda Managed Instances configuration runs a small always-on baseline and uses a scaling script to pre-warm to 50/100/150 EEs in the minutes leading up to each event, then scales back down to baseline afterward.

To simulate a peak load under controlled conditions, the fleet is pre-warmed for a 7-minute window (5-minute ramp and 2-minute burst) then scaled back down. The cost breakdown can be as follows.

Component Volume Rate Cost
API Gateway requests 4.8 M $3.50 per 1 M $16.80
DynamoDB writes 8.8 M WCU $1.25 per 1 M $11.00
Lambda Managed Instances compute (peak window) 75 × c7i.4xlarge × 7 min $0.821 / instance-hr $7.18
Lambda Managed Instances request charges 4.8 M $0.20 per 1 M $0.96
CloudWatch Logs (~2 GB) ingestion $0.50 per GB $1.00
Amazon ElastiCache Serverless for Valkey 4.8 M INCR operations ECPU-based $0.30
Total per burst ~$37.00

The estimated cost for simulating each burst is around $37.

Best practices

Based on experience building this solution, here are key recommendations:

  • Pre-warm before scheduled events. Raise MinExecutionEnvironments using an Amazon EventBridge Scheduler rule or a manual scaling script when you expect major spikes, giving Lambda Managed Instances enough time to scale the underlying instances. Restore the low baseline after the event.
  • Set MaxExecutionEnvironments aggressively. Lambda Managed Instances adds new EEs to your capacity provider. A high MaxExecutionEnvironments value costs nothing while idle but absorbs unexpected demand during the burst.
  • Write-shard hot DynamoDB tables. For workloads writing thousands of items per second to one logical entity (a single event, a single product SKU), spread writes across a synthetic sharded partition key. This sample uses 500 shards per event.
  • Use WarmThroughput on DynamoDB tables. Pre-provision physical partitions before the burst rather than waiting for adaptive capacity to expand during the first minute of the on-sales.
  • Keep hot atomic counters out of DynamoDB. Single-row atomic increments in DynamoDB cap at approximately 1,000 operations per second.
  • Make write endpoints idempotent. The sample uses a caller-provided booking_id on the confirmation endpoint so that retries produce the same booking record instead of duplicates.

Clean up

When you are done exploring the solution, remove the provisioned resources to avoid ongoing charges. For the full cleanup commands and exact steps, refer to the GitHub repository README file.

Conclusion

Lambda Managed Instances brings the same Lambda programming model to workloads that need sustained, pre-provisioned compute during predictable bursts: ticket on-sales, product launches, registration windows, and other scheduled surge patterns. The concert ticketing example shows how a queue-plus-hold-and-confirm pattern built on Lambda Managed Instances can sustain 40,000 requests per second while costing less than an always-on EC2 fleet sized for the same peak.

Explore the Lambda Managed Instances documentation and try building your own predictable-burst serverless application. You can find the complete code for this example in the GitHub repository.


About the authors

Mythili Annamalai Sekar

Mythili Annamalai Sekar

Mythili Sekar is a Solutions Architect at Amazon Web Services (AWS) working with Independent Software Vendors (ISVs), where she guides customers in designing secure, enterprise-scale architectures built on AWS best practices. Her work centers on serverless and generative AI, helping software companies turn new cloud capabilities into real, production-ready outcomes for their businesses.

Guy Haddad

Guy Haddad

Guy is a Senior Technical Account Manager at AWS where he assists customers with leveraging their AWS entitlements and adhering to architectural and operational best practices. He specializes in AI/ML and serverless technologies and has a deep background in software development, telecommunications and complex program deliveries.

Introducing the new AWS WAF security analytics dashboard

Post Syndicated from Praveen Hosur Narayana Gupta original https://aws.amazon.com/blogs/security/introducing-the-new-aws-waf-security-analytics-dashboard/

When blocked requests spike or a customer reports being locked out, a security team has to work out what is happening, where it is happening, and if AWS WAF is making the right call. Currently, that usually means opening each protection pack (web ACL) in turn, across domains, AWS Regions, and Amazon CloudFront distributions, or querying AWS WAF logs. In 2024, we introduced the AWS WAF traffic overview dashboard, which gives you a near real-time view of each protection pack (web ACL). Today, we’re introducing the AWS WAF security analytics dashboard: a single global page that you can use to investigate traffic across all of your protection packs (web ACLs), Regional resources, Amazon CloudFront distributions and then act on what you find. The dashboard can help you investigate and contain threats faster and reduce false positives that block real customers. You don’t need to build or maintain your own log analytics pipeline to do it.

In this post, we introduce the new dashboard and walk you through two use cases: investigating a traffic spike, and tuning your rules to reduce false positives.

Introduction to the security analytics dashboard

To open the dashboard, go to the AWS WAF console and choose Security analytics in the navigation pane. The dashboard shows request data across all protection packs (web ACLs) in your account. You can narrow it to specific protection packs (web ACLs) and set the time range. As shown in the following figure, at the top of the page, you can see total requests split by action (Allow, Block, CAPTCHA, and Challenge). The Requests chart shows how the traffic changes over time. Below that, traffic breakdown widgets show the top values for each dimension. The dashboard is built on full-fidelity request data, not samples.

Figure 1: The security analytics dashboard across all protection packs

Dimensions

You can filter, group, and break down traffic by dimensions that include, but aren’t limited to, the following:

  • Who’s sending traffic – Client IP, country, Autonomous System Number (ASN), user-agent, and JA4 TLS fingerprints
  • What they’re requesting – Host, path (URI), protected resource (Amazon CloudFront distribution, AWS Application Load Balancers, and others), Region, or protection pack (web ACL)
  • How AWS WAF responded – Action, rule triggered, labels, or response code

We’ll continue to add dimensions to the security analytics dashboard over time. The rest of this post refers to the preceding dimensions by the names used here. Two dimensions deserve a closer look:

  • Host – Many customers think about their applications by domain rather than by protection pack (web ACL). Grouping or filtering by Host will show you which of your domains are under attack or if a spike is hitting www, the API, or a staging site, even when one protection pack (web ACL) protects several domains or one domain spans several protection packs (web ACLs).
  • Labels – Labels are metadata that AWS WAF rules add to the requests they inspect. AWS Managed Rules for AWS WAF add them (for example, Bot Control labels for bot category, verification status, and signals such as non_browser_user_agent), and you can create rules to add custom labels. Because labels are recorded even when a rule only counts, filtering by a label shows you what a rule detected across all of your protection packs (web ACLs), without changing how your traffic is handled.

Controls

The dashboard is built around a few controls:

  • Filter requests – Combine conditions on any dimension, using Equals or Does not equal. Filters apply to the whole dashboard: the action split, the Requests chart, every widget, and the request list update to match. Your dashboard view is saved in your browser.
  • Group by – Split the Requests chart by any dimension, such as Host, Rule triggered, Country, or JA4, to see how traffic changes over time.
  • Show only, Exclude, and Block – Select any value in any widget to focus on it, remove it from view, or block it. For example, you can block a high-risk or unexpected IP address, or block traffic from a country, directly from the dashboard.
  • Requests and detections – Review the individual requests behind the charts. For each request, see HTTP request fields such as host, path, headers, user agent, and JA4 fingerprint. You can also see which detections and labels matched and whether each action was enforced or only counted . Previously, this level of detail meant working from a limited sample of requests or setting up and querying your own AWS WAF logs. Now it’s available directly on the dashboard.

Together, these controls help you answer questions such as:

  • What share of traffic across all your protection packs (web ACLs) and domains is being blocked, challenged, or allowed, and how is it changing?
  • Which rules are doing the most work, and are any of them blocking legitimate users?
  • Which IP addresses, ASNs, JA4 fingerprints, or countries are behind a spike, and what are they targeting?
  • How much of your traffic comes from bots, and are the bots verified?

Use case 1: Investigate a traffic spike

Suppose you receive an alert that blocked requests have increased. To investigate:

  1. Go to the Security analytics page in the AWS WAF console and select All protection packs.
  2. Assess the scope: The action split shows the overall block rate. Group the Requests chart by Host to see which domains are affected and check the Protection pack widget to see whether one application or several are involved. A campaign hitting your storefront, API, and media domains at the same time calls for a different response than a problem on a single endpoint.
  3. Identify the source: Group the Requests chart by Rule triggered to see which rules are mitigating the traffic and when they started firing. Then check the source and request dimensions. If one IP address sends a disproportionate share of requests, or many IP addresses share one JA4 fingerprint, the traffic likely originates from a single automated actor.

    Figure 2: Requests grouped by Rule triggered, showing which rules fired and when

  4. Confirm with request-level evidence: When you find an unexpected value, select it and choose Show only to filter the entire dashboard to it.
  5. Then confirm what you’re seeing in Requests and detections. Expanding a request shows all its details, including the HTTP request fields. For example, a curl user agent with no Accept-Language header, coming from a cloud hosting ASN, is likely automated traffic.

    Figure 3: Show only, exclude, or block it

After you confirm the source, choose a response that fits the traffic:

  1. One clear source: Choose Block this IP address directly from the dashboard. Use a geographic block only if you don’t expect legitimate customers from that country.
  2. Traffic spread across multiple IP addresses: Add a rate-based rule with a custom aggregation key such as JA4, or use AWS WAF Bot Control.
  3. Known bad actors and application-layer floods: Add the Amazon IP reputation list and the Anti-DDoS managed rule group.
  4. Faster detection time: Create Amazon CloudWatch alarms on AWS WAF metrics. For details, see Monitoring with Amazon CloudWatch.

When the change is in place, return to the dashboard to confirm that requests from that source now show the Block action.

Use case 2: Tune your rules and reduce false positives

Rules can fail in two ways: by blocking legitimate users, or by only counting traffic that they should stop. Filters and labels help you find both.

If you suspect that a rule is blocking a broad population, such as many distinct clients sending only a few requests each, enter Rule triggered = <rule name> in Filter requests. The dashboard shows only the requests that the rule acted on. Review the Country, Host, and Path (URI) breakdowns to understand who the blocked clients are and what they requested. If the blocked clients look like your typical customers, with common browsers, expected countries, and checkout or login paths, consider adding a scope-down statement to the rule or changing the action to Challenge.

Figure 4: The dashboard filtered to a single rule with Filter requests

Evaluate rules before you enforce them: When you evaluate a managed rule group in Count mode, filter by its labels to see exactly which requests each rule matched. For example, filter by a Bot Control label such as awswaf:managed:aws:bot-control:bot:unverified, then check Host, Path (URI), and User-Agent to see what those bots are after. Use Exclude on labels for known-good traffic, such as bot:verified search engine crawlers, to keep them out of your review.

On the Detections tab of Requests and detections, rows marked Counted, not enforced show what a rule would block. If the matches aren’t partners or monitoring tools, consider changing the rule action to Block.

Figure 5: Record details for a single request, including host, JA4 fingerprint, and protection pack

After you change a rule, compare the same time window on the dashboard to confirm that the rule now affects only the traffic you intended.

Conclusion

The traffic overview dashboard shows you what changed in each protection pack (web ACL). The security analytics dashboard helps you understand why it changed, and lets you act on it from the same page, across all of your protection packs (web ACLs), domains, Regions, and Amazon CloudFront distributions. Filters, grouping, and labels explain the traffic, and request-level evidence helps you act with more confidence. Together, they can help you investigate faster, reduce how often real users are blocked by mistake, and confirm that each rule changes affect the traffic you intend.

The security analytics dashboard is available at no extra cost in all AWS Regions where AWS WAF is offered, and shows up to 21 days of request data. To get started, open the AWS WAF console and choose Security analytics.

If you have feedback about this post, submit comments in the Comments section below.

Related reading

To learn more about visibility and bot management in AWS WAF, see the following resources:

If you have questions about this post, contact AWS Support or start a new thread on AWS re:Post.

Praveen Hosur Narayana Gupta

Praveen Hosur Narayana Gupta

Praveen is a Solutions Architect at AWS specializing in Edge, Networking, and Security services. He helps customers build secure, high-performance applications and protect them from Bots and DDoS attacks. Outside work, he’s an avid bird watcher and wildlife photographer.

Mohit Mysore

Mohit Mysore

Mohit is a Senior Technical Account Manager at AWS specializing in network and edge security. He helps customers protect their applications and strengthen their security posture at scale. Outside work, he enjoys traveling, watching soccer and Formula 1, and spending time with his family.

Kaustubh Phatak

Kaustubh Phatak

Kaustubh is a product leader specializing in AI/ML systems and enterprise security solutions. He has led cross-functional teams in deploying AI-powered products at scale, working closely with security architects and CISOs to address the intersection of AI innovation and cybersecurity risk. His work focuses on translating complex technical capabilities into business value, particularly in emerging technology domains where traditional frameworks don’t apply.

CVE-2026-123890: Critical Authentication Bypass in VMware vCenter

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/etr-cve-2026-123890-critical-authentication-bypass-vmware-vcenter

Overview

On November 19, 2026, Broadcom published VMware Security Advisory VMSA-2026-0009, addressing five vulnerabilities in VMware products. The most severe of these, CVE-2026-123890, is an authentication bypass using an alternate path or channel (CWE-288) in the VMware Directory Service component of vCenter. Broadcom assigned the vulnerability a critical CVSSv3 score of 9.8.

A malicious actor with network access to an affected vCenter deployment may exploit CVE-2026-123890 without credentials to bypass authentication and gain unauthorized access to the system as the Administrator user. Mandiant privately reported the issue to Broadcom. Also, Mandiant/Google Threat Intelligence confirmed in-the-wild exploitation of CVE-2026-123890 by Chinese state-linked threat actor ARMORY CASTLE as early as September 2026.

CVE-2026-123890 is distinct from the vCenter authentication bypass vulnerability CVE-2026-59309 that Broadcom addressed earlier in 2026. The vendor FAQ states that all vCenter systems below the versions fixed by VMSA-2026-0009 require the new update, including systems that already received the earlier fix. Broadcom characterizes the vCenter update as an emergency change requiring prompt action.

Mitigation guidance

Vendor-provided updates are available for CVE-2026-123890. Broadcom lists no workaround, and the patches cannot be applied using vCenter Quick Patch. Organizations should prioritize upgrading vCenter on an emergency basis, outside of normal patch cycles, using the standard update mechanism for their deployment.

VMware Product

Affected Version

Fixed Version / Patch

VMware Cloud Foundation / vSphere Foundation

9.1.x.x

9.1.1.0200

VMware Cloud Foundation / vSphere Foundation

9.0.x.x

9.0.2.0200

VMware vCenter Server

8.0

8.0 U3m

VMware vCenter Server

7.0

Contact Broadcom Support (extended-support customers)

VMware Cloud Foundation

5.x

5.2.5

VMware Telco Cloud Platform

3.0, 4.x, 5.0.x, 5.1.x, 5.2

8.0 U3m — KB463116

VMware Telco Cloud Infrastructure

3.0

8.0 U3m — KB463116

The fixes are cumulative. The vCenter 8.0 U3m and 9.0.2.0200 updates introduce a “Back-in-Time” restriction that blocks upgrades to VMware Cloud Foundation 9.1.1; Broadcom advises customers in an active upgrade to review the vendor FAQ and interoperability matrix. Updating vCenter temporarily makes its management interfaces unavailable, but Broadcom states that running virtual machine and container workloads continue to operate.

For the latest affected-version and mitigation guidance, please refer to Broadcom’s security advisory and supplemental FAQ.

Rapid7 customers

Exposure Command, Vulnerability Management, and Nexpose

Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-123890 on VMware vCenter Server with an unauthenticated vulnerability check expected to be available in the Nov 20, 2026 content release.

Updates

  • November 19, 2026: Initial publication.

Introducing Amazon EMR Serverless Flex: Run non-urgent Spark jobs at a discount

Post Syndicated from Neil Mukerje original https://aws.amazon.com/blogs/big-data/introducing-amazon-emr-serverless-flex-run-non-urgent-spark-jobs-at-a-discount/

With Amazon EMR Serverless, you can run Apache Spark applications without provisioning or managing clusters. You submit jobs, EMR Serverless allocates the compute, scales it during execution, and releases it when the job finishes. There are no clusters to tune and no idle capacity to pay for. Since launch, customers have used EMR Serverless to run production extract, transform, and load (ETL) pipelines, machine learning (ML) feature engineering, and large-scale data transformations, replacing Spark clusters that required dedicated engineering effort to operate.

Customers also have workloads that aren’t time-sensitive. On EMR on EC2 or self-managed Spark clusters on EC2, teams use Amazon Elastic Compute Cloud (Amazon EC2) Spot Instances to run these workloads on spare compute capacity at a lower cost. For top EMR customers, EC2 Spot Instances are a key cost-optimization lever, with many running a portion of their workloads on spare capacity. For customers looking to modernize from clusters to serverless to lower their operational overhead, the absence of an equivalent option on EMR Serverless meant they could only move part of their platform. The time-sensitive workloads came over, but the cost-optimized workloads running on spare capacity stayed on EC2 Spot Instances. Spare capacity support on EMR Serverless has been one of the most requested features, with customers telling us it’s a prerequisite for full migration.

Today we are launching Amazon EMR Serverless Flex, a new execution option that runs Spark batch jobs on spare compute capacity at a fixed 60 percent discount compared to standard pricing. With Flex, EMR Serverless now offers two execution options: Standard for workloads that need predictable start times and dedicated resources, and Flex for workloads where cost matters more than execution-time predictability. Customers who previously split their Spark platforms between EMR Serverless and EMR on EC2 or self-managed clusters on Spot Instances can now consolidate onto a single serverless platform. Customers who didn’t consider EMR Serverless at all, because spare capacity support was missing, can now evaluate EMR Serverless as a full replacement for their cluster-based deployments.

Why Flex matters for your Spark platform

When we talk to customers running Spark at scale, we see a common pattern: two tiers of workloads with different cost and reliability requirements.

Time-sensitive production workloads – ETL pipelines that feed dashboards, ML models, and downstream applications on a schedule. These need fast startup, dedicated compute, and predictable completion times. On EMR Serverless, these run on the Standard execution option.

Non-urgent batch workloads – Pre-production validation, test and development runs, backfills, nightly batch transformations, one-time data loads, and recurring reports with generous processing windows. These jobs are cost-sensitive but time-flexible. They need to finish, but not on a strict deadline.

On EMR on EC2 or self-managed Spark clusters on EC2, customers often deploy non-urgent workloads on Spot Instances. But without a spare-capacity option on EMR Serverless, moving to serverless meant giving up the cost lever on non-urgent batch workloads.

What it takes to run Spark on spare capacity today

On EMR on EC2, running Spark on Spot Instances is a shared responsibility between the service and the customer.

What the EMR service provides: EMR on EC2 provides the infrastructure features for running workloads on spare capacity:

  • Instance fleets with Spot allocation strategies (capacity-optimized) that spread capacity requests across instance types and Availability Zones.
  • Graceful decommissioning that gives Spark time to migrate shuffle data and finish running tasks when a Spot Instance receives a 2-minute termination notice.
  • Spark resilience enhancements (decommission-aware task scheduling, exclusion of decommissioning nodes, and shuffle block tracking) that help Spark recover from node loss without getting stuck on fetch failures.

What customers implement: Based on best practices that have evolved over the years, here’s what teams have built and maintained on top of the preceding EMR features:

  • Instance fleet diversification – Select the right mix of instance types across instance variants (m5, m5a, m5d, r5, r5a, r5d) that meet vCPU and memory requirements. Use the Spot Instance Advisor to target types with lower interruption rates. Configure allocation strategies and fallback behavior.
  • Multi-AZ placement – Launch clusters targeting multiple Availability Zones to tap into the capacity in the entire AWS Region.
  • Driver protection with YARN node labels – Configure YARN node labels to pin the Spark driver to On-Demand core nodes, keeping it off Spot task nodes. If the driver lands on a Spot Instance and that instance is reclaimed, the entire job fails. Setting this up requires YARN label configuration, node-label expression settings in Spark, and ongoing validation.
  • Configuring resilience and decommissioning settings – Tune decommissioning timeouts, understand how the Spark resilience enhancements work, and configure them correctly for each workload.
  • Ongoing tuning and debugging – Monitor interruption rates by instance type, adjust fleet composition as Spot pricing shifts, debug capacity-related job failures, and maintain the configuration as EMR release versions change.

What Flex handles for you

EMR Serverless Flex applies all of these spare-capacity best practices on your behalf. You add one parameter to your job submission with no fleet configuration or YARN tuning. EMR Serverless takes on the responsibility of running your workloads on spare capacity:

  • AZ selection – EMR Serverless evaluates spare capacity pools across Availability Zones in the AWS Region and places workers where capacity is most available.
  • Instance diversification – EMR Serverless spreads executors across multiple instance types and generations so that reclamation of one instance type doesn’t hit all workers at once.
  • Driver protection – The Spark driver runs on a dedicated Standard worker that isn’t subject to spare capacity reclamation. The driver holds job state (the directed acyclic graph, stage progress, and task assignments) so protecting it prevents job failure, without YARN node labels to configure.
  • Decommission-aware scheduling and worker exclusion – When a Flex worker receives a 2-minute reclamation notice, EMR Serverless stops scheduling new tasks on that worker and excludes it from future assignments. The Spark resilience enhancements that EMR developed for handling node loss (decommission-aware task scheduling, proactive worker exclusion, and shuffle block tracking) are applied automatically.
  • Automatic task retry – Spark’s built-in fault tolerance retries affected tasks on healthy Flex workers. The job continues without manual intervention.
  • Shuffle offload with Serverless Storage (optional) – With EMR Serverless Storage, shuffle data is written to remote storage instead of local disk. When a reclaimed executor’s tasks are retried, the new executor reads the stored upstream shuffle output instead of recomputing it, reducing the fetch-failure problem for shuffle-heavy jobs.

All existing EMR Serverless capabilities (AWS Lake Formation fine-grained access control, AWS Graviton support, AWS Glue Data Catalog integration, and data source connectors) work the same with Flex jobs.

What happens when you run a Flex job

Here is the life cycle of a Flex job from submission to completion:

  1. Job submission – You submit a Spark job with Flex enabled. EMR Serverless accepts the job and begins acquiring spare compute capacity.
  2. Capacity acquisition – EMR Serverless selects an Availability Zone within the chosen Region where spare capacity is most available and requests workers across a diverse set of instance types and generations. The Spark driver starts on a dedicated Standard worker.
  3. Job execution – Executors run on Flex workers. The job proceeds as it would on Standard using the same Spark runtime and APIs.
  4. If capacity is reclaimed – When a Flex worker receives a reclamation notice, EMR Serverless excludes it and stops scheduling new tasks on it. Spark retries the affected tasks on healthy Flex workers. If you have Serverless Storage enabled, retried tasks read stored shuffle data instead of recomputing upstream stages. Billing for the reclaimed worker stops at reclamation.
  5. Completion – The job completes and results are written to the output location.
  6. Failure handling – If no executor joins the driver within 20 minutes of job start, the job fails. To recover from failures, resubmit the job using the best practices you apply to restart a failed job.

How Flex workers are billed

Flex workers are billed at a fixed 60 percent discount on vCPU-hours and memory GB-hours compared to Standard workers. The Spark driver runs on a Standard worker and is billed at the Standard rate. The discount is fixed and unlike EC2 Spot doesn’t fluctuate with supply and demand.

Each worker is billed for the time it was part of the job run, per second with a 1-minute minimum. When a Flex worker is reclaimed, billing for that worker stops. For example, if a 10-minute job runs 20 Flex workers and 3 of them are reclaimed after 5 minutes, you are billed for 17 workers at 10 minutes and 3 workers at 5 minutes.

Flex spend appears as separate line items in AWS Cost Explorer and on your bill, so you can distinguish Flex spend from Standard spend. Flex also works with job-level cost allocation tags, so you can continue attributing costs by team or project. For pricing details, see Amazon EMR pricing.

Flex in practice: Resilience and cost

We ran a 103-query decision-support benchmark (derived from TPC-DS 1 TB and 3 TB scale factor) on Spark to compare Flex and Standard at two data scales. Both runs used the same queries, worker configuration, and release label (emr-7.14.0).

Scale factor Execution Queries completed Wall-clock time Estimated cost Total executors used Executors reclaimed Task failures
1 TB Standard 103 of 103 11.5 min $5.68 12 0 0
Flex 103 of 103 12.3 min $2.07 (64% savings) 15 1 0
3 TB Standard 103 of 103 12.4 min $6.29 12 0 0
Flex 103 of 103 16.1 min $2.32 (63% savings) 21 1 0

Resilience: In each Flex run, we observed one executor reclaimed mid-job. EMR Serverless excluded the reclaimed worker, and Spark retried the affected tasks on healthy executors. All 103 queries completed in both runs, with zero job resubmissions.

Cost: For this benchmark, we saw Flex reduce estimated cost by about 63 percent at both data scales, from $5.68 to $2.07 at 1 TB, and from $6.29 to $2.32 at 3 TB.

Note: The actual savings and frequency of reclamations will vary by workload, Region, and available spare capacity at the time of execution. We recommend running your own workloads on both Flex and Standard to establish a baseline. This workload is derived from the TPC-DS Benchmark and isn’t comparable to published TPC-DS Benchmark results, as this implementation doesn’t comply with all requirements of the TPC-DS Benchmark.

Runtime tradeoff – The 1 TB Flex run took 7 percent longer than Standard. The 3 TB run took 30 percent longer. The gap widened at larger scale because the reclaimed executor’s tasks needed more time to recompute. Flex jobs can also take longer to start if spare capacity isn’t immediately available. Flex works well for any job where the completion deadline is flexible, including short jobs. A job that runs in 10 minutes on Standard and 12 minutes on Flex is a good candidate if it doesn’t have a strict service level agreement (SLA).

Getting the best results from Flex

Three practices we recommend to get the most from Flex:

Avoid top-of-the-hour peaks

We observe that spare capacity availability drops when many jobs start simultaneously at the top of each hour. Shifting your job start times by even a few minutes (for example, submitting at 9:20 instead of 9:00) reduces contention for spare capacity and improves the chance of a fast start.

Run outside business hours when possible

Spare capacity is most available when overall compute demand is lower. We see the best availability when customers schedule non-urgent workloads to run after 6:00 PM in the Region, or on weekends, giving Flex jobs access to deeper capacity pools with fewer interruptions.

Use Serverless Storage

EMR Serverless Storage writes shuffle data to remote storage, so retried tasks read stored intermediate results instead of recomputing upstream stages. This reduces the runtime cost of interruptions on shuffle-heavy jobs and adds another layer of resilience.

Getting started

Flex is a job-run setting. You create your EMR Serverless application as usual and add one parameter when submitting a job:

aws emr-serverless start-job-run \
    --application-id <application-id> \
    --execution-role-arn <job-role-arn> \
    --flex-execution '{"enabled": true}' \
    --job-driver '{
        "sparkSubmit": {
            "entryPoint": "s3://<bucket>/scripts/my-spark-job.py"
        }
    }'

In EMR Studio, select the Enable Flex execution checkbox when submitting a job, as shown in the following screenshot:

EMR Studio job submission form with the Enable Flex execution checkbox selected

Figure 1: Enable Flex execution checkbox in the EMR Studio job submission form

You can run Flex and Standard jobs on the same application. For step-by-step instructions, see the Amazon EMR Serverless User Guide.

Conclusion

In this post, we shared how Amazon EMR Serverless Flex runs non-urgent Spark batch jobs on spare compute capacity with built-in resilience features, closing a gap that previously blocked customers from modernizing their entire Spark platforms onto EMR Serverless.

To get started, pick a non-critical job, submit it with --flex-execution '{"enabled": true}' and compare the cost and runtime against your Standard baseline. For more detail, see the Amazon EMR Serverless User Guide.


About the authors

Neil Mukerje

Neil Mukerje

Neil is a Principal Product Manager at Amazon Web Services. He is driven to build experiences that let customers achieve their goals efficiently. In his spare time, he enjoys reading, hiking, and tinkering with technology.

Manjeet Chayel

Manjeet Chayel

Manjeet serves as Big Data Manager, Worldwide Specialist Solutions Architects at AWS, where he leads a global team of specialist architects driving customer-facing engagements across Amazon EMR, AWS Glue, and the broader Big Data Analytics portfolio.

Announcing 30-minute timeout for on-demand AWS Lambda Event Functions

Post Syndicated from Tarun Rai Madan original https://aws.amazon.com/blogs/compute/announcing-30-minute-timeout-for-on-demand-aws-lambda-event-functions/

AWS Lambda now supports a 30-minute function timeout for Event Functions that run on demand, doubling the previous 15-minute limit for synchronous, asynchronous, and event source mapping (ESM) invocations. On Lambda Managed Instances, synchronous invocations also support up to 30 minutes, while asynchronous and ESM invocations keep the 90-minute timeout we announced in September 2026. You can now run AI inference, media transcoding, and financial calculations on Lambda for spiky or steady-state traffic without re-architecting your applications. The new timeout also applies when you use Lambda durable functions or invoke your functions from AWS Step Functions Standard workflows.

Evolution of function timeout on Lambda

Lambda launched in 2014 with a 60-second function timeout, which we extended to 5 minutes in 2015 and to 15 minutes in 2018.

Lambda now offers three form factors: Event Functions, Web Functions, and MicroVMs. Event Functions process events from more than 200 AWS event sources through synchronous, asynchronous, and ESM invocations. With Web Functions, you can run HTTP servers on Lambda with an HTTP-native, multi-concurrent programming model and opt-in multi-Region endpoints. MicroVMs give each user or session an isolated environment for running user-generated or AI-generated code.

By default, all three form factors run on demand, with Lambda provisioning compute as requests arrive. For steady-state traffic, Event Functions can also run on the Lambda Managed Instances capacity provider. With Lambda Managed Instances, you can process multiple concurrent requests per instance and choose specialized compute configurations, without managing infrastructure. You can also use EC2 pricing options such as AWS Savings Plans and Reserved Instances. Figure 1 shows the form factors.

The three Lambda form factors: Event Functions, Web Functions, and MicroVMs

Figure 1: Lambda form factors

Each form factor has its own duration limit (Table 1). Until today, Event Functions had a 15-minute timeout, except for asynchronous and ESM invocations on Lambda Managed Instances, which we extended to 90 minutes in September 2026.

Lambda durable functions run on demand and on Lambda Managed Instances, and provide application-level checkpointing and workflow-as-code. Your code saves execution state with step() and wait() operations and resumes from the last checkpoint after a failure. A durable execution (the complete lifecycle of a durable function) can run for up to 1 year, but each invocation within it is bound by the function timeout.

Customers told us that 15 minutes was still too short for many Event Functions workloads that run on demand, and for synchronous invocations on Lambda Managed Instances. Agentic AI requests that chain model calls and tool invocations can take longer than 15 minutes to return a result. Media transcoding and file conversion jobs often run past 15 minutes when input files are large. Financial calculations such as Monte Carlo simulations, bond pricing, and portfolio risk analysis are memory-intensive and need more continuous execution time. Report generation across multiple data sources can also exceed 15 minutes during peak volumes. ETL steps triggered by Amazon Simple Queue Service (Amazon SQS) or Amazon Simple Storage Service (Amazon S3) events can run just as long. Many of these workloads have spiky traffic that doesn’t justify steady-state capacity on Lambda Managed Instances.

With today’s launch, Event Functions support up to 30 minutes for synchronous, asynchronous, and ESM invocations, and up to 90 minutes for asynchronous and ESM invocations on Lambda Managed Instances. Table 1 shows the maximum durations across Lambda form factors.

Duration Event Functions Web Functions MicroVMs
On demand (default) Lambda Managed Instances
Without durable execution

Synchronous: 30 minutes

Asynchronous: 30 minutes

ESM: 30 minutes

Synchronous: 30 minutes

Asynchronous: 90 minutes

ESM: 90 minutes

15 minutes 8 hours (running and suspended)
With durable execution

Synchronous: 30 minutes

Asynchronous: 1 year

ESM: 30 minutes

Synchronous: 30 minutes

Asynchronous: 1 year

ESM: 90 minutes

– –

Table 1: Supported durations on Lambda form factors

Configuring the 30-minute function timeout

You can configure any Event Function with a timeout of up to 30 minutes (1,800 seconds). For asynchronous and ESM invocations on Lambda Managed Instances, you can configure up to 90 minutes (5,400 seconds). Lambda rejects higher values with a validation error. Your function runs exactly as before, with the same runtime, handler, IAM execution role, and virtual private cloud (VPC) configuration. The Init phase keeps its existing limits of 10 seconds for functions that run on demand and 15 minutes on Lambda Managed Instances. Provisioned concurrency and Lambda SnapStart, which aren’t available on Lambda Managed Instances, keep their 15-minute initialization limit.

To set the timeout, update your function configuration using the AWS Command Line Interface (AWS CLI):

aws lambda update-function-configuration \
--function-name my-demo-function \
--timeout 1800 \
--region us-east-1

To set the timeout in an AWS Serverless Application Model (AWS SAM) template, use the Timeout property:

MyFunction:
  Type: AWS::Serverless::Function
  Properties:
    FunctionName: my-demo-function
    Runtime: python3.14
    Handler: app.handler
    Timeout: 1800
    MemorySize: 2048

You can also update the timeout in the Lambda console under Configuration > General configuration (Figure 2), where synchronous test invocations now run for up to 30 minutes. If you use an AI coding assistant such as Kiro, Claude Code, or Codex, you can install the Agent Toolkit for AWS and configure the timeout with natural language prompts.

Lambda console General configuration page with the function timeout set to 30 minutes

Figure 2: Configuring Lambda function timeout

The new timeout applies to invocations that start after you update the function. For event source mappings, allow a few minutes for the change to propagate. Amazon CloudWatch metrics, AWS CloudTrail, and AWS X-Ray continue to capture the full invocation lifecycle. For details, see monitoring Lambda functions and monitoring durable functions.

For Event Functions that run on demand, the 30-minute timeout is available in all commercial AWS Regions. For synchronous invocations on Lambda Managed Instances, it is available in all AWS Regions where Lambda Managed Instances is available. Standard AWS Lambda pricing applies.

30-minute timeout and durable functions

The 30-minute function timeout and durable functions are complementary. The function timeout (--timeout) controls how long each individual invocation can run, whereas the durable execution timeout (ExecutionTimeout in --durable-config) controls the total elapsed time from execution start to completion. On replay after a failure, the function re-executes from the beginning and skips completed steps.

Functions that run on demand: Each durable function invocation can run for up to 30 minutes, whether you invoke it synchronously, asynchronously, or through an event source mapping. When you invoke the function asynchronously, the durable execution can run for up to 1 year. When you invoke it synchronously through the Invoke API or a function URL, the durable execution is limited to 30 minutes, and Lambda rejects higher values. ESM invocations have the same 30-minute limit.

Lambda Managed Instances: Synchronous invocations can run for up to 30 minutes, and asynchronous and ESM invocations can run for up to 90 minutes. When you invoke the function asynchronously, the durable execution can run for up to 1 year. The durable execution is limited to 30 minutes for synchronous invocations and 90 minutes for ESM invocations.

For idempotent jobs, such as an ETL step triggered by Amazon SQS, the extended timeout alone might be enough. A failed invocation returns the message to the queue for a fresh attempt. For jobs where re-execution is expensive, combine the extended timeout with durable functions. A 25-minute inference run that fails at minute 22 restarts from zero without checkpoints, but resumes from its last checkpoint with durable functions.

Invocation behavior: Synchronous, asynchronous, and event source mappings

Synchronous invocations (up to 30 minutes): Synchronous invocations now support up to 30 minutes, whether the function runs on demand or on Lambda Managed Instances. If another AWS service invokes your function synchronously, that service applies its own timeout, so verify that it supports the longer duration before you raise the function timeout. Set your client’s read and socket timeouts longer than the function timeout. For example, increase the read timeout of your AWS SDK client when you call the Invoke API. On Lambda Managed Instances, Lambda applies the 30-minute limit to synchronous invocations even if the function timeout is higher, and the GetFunctionConfiguration API reports the configured value.

Asynchronous invocations (up to 30 minutes, or up to 90 minutes on Lambda Managed Instances): If the function fails or times out, Lambda applies your configured retry policy (up to two retries by default). It then routes failed events to your dead-letter queue or on-failure destination.

Event source mappings (up to 30 minutes, or up to 90 minutes on Lambda Managed Instances): For SQS, set the queue’s visibility timeout to at least six times the function timeout, so at least 3 hours for a 30-minute function. This gives Lambda enough time to retry if a function is throttled while it processes a previous batch. Lambda validates this when you create the event source mapping, but it doesn’t prevent later changes to queue or function settings that create a mismatch.

For Amazon Kinesis Data Streams and Amazon DynamoDB Streams, Lambda processes one batch per shard at a time by default, so longer invocations slow how quickly each shard is read. Monitor the IteratorAge metric and increase the parallelization factor if records start to back up. Longer invocations also mean that a failure late in a batch wastes more work. Enable partial batch failure reporting so that Lambda retries only the failed records. You can use it with SQS, Amazon Kinesis, DynamoDB Streams, Amazon Managed Streaming for Apache Kafka (Amazon MSK), and self-managed Apache Kafka event source mappings.

Invocations from Amazon MQ (ActiveMQ and RabbitMQ) and Amazon DocumentDB (with MongoDB compatibility) event source mappings remain limited to 14 minutes. The same limit applies to Kafka event source mappings that were created before November 19, 2026, and don’t use provisioned mode. To use the 30-minute timeout with Kafka, create a new event source mapping or turn on provisioned mode for your existing one. For these mappings, keep the function timeout at 14 minutes (840 seconds) or less.

Considerations and best practices

Longer-running functions need extra care with concurrency and components that can expire mid-invocation, such as network connections and credentials.

Concurrency: Concurrency equals requests per second multiplied by average duration in seconds. At the same request rate, a function that runs for 30 minutes instead of 15 needs twice the concurrency. For example, 1 request per second at 30 minutes each needs 1,800 concurrent executions. Check your account concurrency quota and reserved concurrency settings before you raise the timeout. On Lambda Managed Instances, check the maximum scaling limits of your capacity provider.

Networking: Make sure idle connection timeouts on downstream services such as Amazon Relational Database Service (Amazon RDS), Amazon ElastiCache, and external APIs accommodate the full function duration. If your function routes traffic through a NAT gateway, which drops idle connections after 350 seconds, send keep-alive packets. For long synchronous invocations, also turn on TCP keep-alive on the calling client. DNS caching depends on your runtime and HTTP client. For example, the AWS SDK for Java relies on the JVM DNS cache, which on some configurations never refreshes. Set a short DNS TTL, such as 5 seconds for the JVM, and configure custom HTTP clients to re-resolve hostnames.

Credentials: If your function acquires temporary credentials or tokens, verify they remain valid for the full execution duration or refresh them in the background.

Idempotency: Lambda does not guarantee exactly-once processing, and longer-running functions widen the window for retries and duplicate deliveries. Use Powertools for AWS Lambda to make operations such as payments or database writes idempotent. In durable functions, steps have at-least-once execution semantics by default. The SDK skips completed steps during replay, but steps that fail before checkpointing might re-execute. You can use execution names as idempotency keys for durable functions.

Conclusion

The 30-minute function timeout brings longer continuous execution to Event Functions that run on demand and to synchronous invocations on Lambda Managed Instances. It complements the 90-minute timeout for asynchronous and ESM invocations on Lambda Managed Instances that we launched in September 2026. Workloads such as AI inference, media transcoding, and report generation that exceed 15 minutes can now run on Lambda without architectural workarounds, for spiky or steady-state traffic. If your workloads need a longer timeout, let us know on the AWS Lambda Roadmap GitHub page.

To get started, update your function’s timeout configuration and deploy. For details, see Configure Lambda function timeout in the AWS Lambda Developer Guide. For sample code that shows long-running functions with durable checkpointing, see durable functions examples. To learn more, visit the AWS Lambda product page.


About the authors

Tarun Rai Madan

Tarun Rai Madan

Tarun is a Principal Product Manager at Amazon Web Services (AWS), where he leads product areas across AWS Serverless Compute, including developer and agentic experiences, event-driven data ingestion, orchestration, and compute for data-intensive workloads. His work centers on removing infrastructure complexity so developers can concentrate on their differentiated business logic. Before joining AWS, he was an engineering leader in the semiconductor industry, where he developed high-performance processors for data center, wireless, and automotive applications.

Dan Slusariuc

Dan Slusariuc

Dan is a Software Development Manager at AWS, where he leads the Lambda Frontend team. His team builds the backend services that receive and route Lambda function invocations. He also leads compliance and availability for Lambda. In his prior role, Dan was a Software Development Engineer in Amazon Advertising, where he helped build the engine that generates banners for products listed on Amazon.

Snehil Ameta

Snehil Ameta

Snehil is a Software Development Engineer at AWS, where he works on AWS Lambda. He focuses on Lambda scalability and availability, and leads capabilities such as Lambda response streaming and Lambda Managed Instances. In his prior role, Snehil worked in Amazon seller services, where he helped build its recommendation service.

How AWS Security Incident Response triages your security findings

Post Syndicated from Anatoliy Kochetov original https://aws.amazon.com/blogs/security/how-aws-security-incident-response-triages-your-security-findings/

AWS Security Incident Response continuously triages the threat findings from Amazon GuardDuty and AWS Security Hub CSPM, but most of that work never shows up as a case. If cases are all you look at, it’s hard to tell whether the service is working at all, and that’s the question I hear most often when I help customers onboard. The Proactive response dashboard gives you a high-level view of this activity, and this post takes you behind the numbers to show what happens to an individual finding.

In this post, I walk you through what happens to a finding after it’s ingested by the service, what gets triaged, where each finding is sent, and how a triage decision becomes a case. I then show you how to confirm triage is working day-to-day, so your team can focus on the findings that require attention. The process flow is shown in Figure 1.

Figure 1: AWS Security Incident Response triage flow, from ingestion through to one of three outcomes

Figure 1: AWS Security Incident Response triage flow, from ingestion through to one of three outcomes

Ingestion

AWS Security Incident Response ingests threat findings from GuardDuty through Amazon EventBridge rules that are automatically deployed to your accounts during the onboarding process.

If you send third-party detection findings to Security Hub CSPM from tools such as CrowdStrike, Trend Micro, or Lacework, their threat detection findings are also ingested. Each of those findings must carry complete payload information such as resource ID, account ID, timestamp, and threat details. GuardDuty findings are ingested directly, so these findings aren’t re-ingested through Security Hub CSPM and there’s no duplication.

Triage

The service triages findings that indicate an active threat, such as compromised credentials, cryptomining, or data exfiltration. These represent activity that’s underway or has already occurred.

Posture and compliance findings aren’t triaged. A misconfiguration or a failed benchmark check reflects the state of your environment rather than an active threat, so those findings remain for your team to address through your existing remediation process.

Outcomes

For each threat finding, the service runs an automated triage process. It evaluates the finding payload, related AWS activity from AWS CloudTrail and Amazon VPC Flow Logs, AWS threat intelligence, and the context you provide about your environment. The service then maps the finding against a profile of known-good activity. What fits the profile is treated as expected, and what doesn’t is flagged for a closer look.

What happens next depends on that outcome. A finding is sent to one of three places:

  • Archived, no action needed – Automated triage or an AWS Security Incident Response engineer confirms the activity is benign or expected. The finding is archived in GuardDuty, with no case and no customer contact.
  • A proactive case is opened – Triage can’t confirm the activity is benign. This is either Unconfirmed Activity (the service needs you to confirm whether it’s expected) or Inappropriate/Unintended Activity (confirmed activity that needs your action). A proactive case is opened, your incident response team is engaged, and the finding stays Current until it’s resolved.
  • Retained for your review, no case – Posture-related findings, such as overly permissive policies, configuration, or missing encryption, aren’t threats. By design, they stay Current without archiving and no case is created.

When a proactive case is opened, you respond to it in the AWS Management Console for AWS Security Incident Response under Cases, where you can communicate directly with the team, share context, and resolve or reopen the case. Timely responses also help the service learn your environment, which helps reduce false positives over time. For the full workflow, see Responding to an AWS generated case.

The preceding outcomes use GuardDuty terms, because it’s the primary source. Third-party findings ingested through Security Hub CSPM follow the same triage logic, but their disposition shows as a workflow-status change rather than archiving. The finding moves from NEW to NOTIFIED when triage begins, which removes it from the default Security Hub CSPM view. If triage clears it as benign, it moves to SUPPRESSED. Otherwise it stays visible for your review.

Because only benign findings are archived, it’s normal to see many findings in Current, and that isn’t a sign the service missed them. Across customers, less than 1 percent of ingested findings result in a customer-facing escalation. Most are handled automatically, without a case.

Credential exfiltration finding example

Suppose GuardDuty generates an UnauthorizedAccess:IAMUser/InstanceCredentialExfiltration.OutsideAWS finding: temporary credentials created on an Amazon Elastic Compute Cloud (Amazon EC2) instance were used from an IP address outside AWS. Triage cross-references the payload against what it knows about your environment.

  • Cleared – The external IP belongs to a corporate virtual private network (VPN) range that your workloads regularly call through, and the service has seen this pattern before. The finding is archived in GuardDuty.
  • Escalated – The IP is in a hosting-provider range with no prior association to your accounts, and the AWS Identity and Access Management (IAM) role has never made calls from outside AWS. The service creates a proactive case, notifies your incident response team, and an engineer investigates whether the credentials were compromised.

Same finding type, two outcomes. The difference is context, and context is what triage builds by observing your environment over time.

How triage sharpens over time

The service builds a profile of what’s normal in your environment. It learns the IP ranges and domains you trust, and the IAM principals and behaviors your workloads rely on. When your team routinely connects from a known VPN range, or a specific IAM role runs nightly batch jobs, the service recognizes those patterns and measures new findings against them. Early on, engineers investigate more findings by hand as they learn your environment. Within a few weeks, automated triage handles most of those decisions on its own.

Triage is dynamic. A finding treated as expected today can be re-evaluated tomorrow if the context changes, so the service can still catch a real threat that reuses a pattern it formerly treated as safe. You can shape the profile by submitting known-good activity, such as trusted IP ranges or authorized scanning tools, through an AWS Support case. For details, see Submit known-good activity.

Archiving versus suppression

It’s possible to conflate the two mechanisms, so it’s worth separating them:

  • Archiving is the primary mechanism. When automated triage or an engineer determines a finding is benign, the service archives it in GuardDuty. The finding then stays there for 90 days.
  • Suppression rules are less common and work differently. A suppression rule acts on future findings. When the service identifies a recurring pattern of expected activity, it might create a GuardDuty suppression rule that automatically archives matching findings so they don’t generate new alerts. Suppressed findings aren’t sent to your configured export, such as an Amazon Simple Storage Service (Amazon S3) bucket or SIEM. When the service creates a rule, your incident response team is notified, and you can view and manage it in the GuardDuty console under Suppression rules.

A healthy deployment typically shows many archived findings and few or no suppression rules. That’s expected, and it means the service is handling findings dynamically rather than relying on static filters.

How to see what triage is doing

Triage runs on its own, and the service gives you a few ways to confirm it’s working.

Proactive response dashboard

The Dashboard page in the AWS Security Incident Response console has a Proactive response section. It counts how many findings were ingested, triaged, investigated, and escalated over the timeframe you select, the last 7, 30, or 90 days.

The Overview leads with two figures. Noise reduction is the share of ingested findings that automated triage resolved without opening a case, so you can see for yourself how much volume never reached your team. Time saved estimates the analyst hours that automation returned to you, counted as one hour for each ingested finding.

Below that, Finding evaluations breaks those stages down:

  • Ingest – Threat findings collected from your detection sources
  • Triage – Findings evaluated automatically to decide whether the activity is expected
  • Investigation – Findings automated triage couldn’t confirm, passed to an AWS Security Incident Response engineer for a closer look
  • Escalation – Investigations raised as a case when a genuine risk was detected or the activity couldn’t be confirmed as expected

A flow diagram on the dashboard shows how those findings move from their sources through triage and investigation, with branches for the ones closed as false positives and the ones still in progress. For more, see Viewing proactive response metrics.

Monthly report

The monthly report is the periodic companion to the dashboard. AWS Security Incident Response emails it to your incident response team a week or two after each month closes. It opens with the accounts monitored, findings processed, and investigations, then lists each investigation and its status, the triage flows that show the checks run for each finding type, and the context the service has learned about your environment, such as the trusted networks it now recognizes as normal.

Archived findings in GuardDuty

For a quick confirmation outside either view, open Findings in the GuardDuty console and filter to see Archived. That list also includes findings archived by you or by suppression rules, so look for the threat findings AWS Security Incident Response archived after triage. Each one is a finding that the service cleared as benign so your team didn’t have to.

Conclusion

AWS Security Incident Response continuously evaluates your threat findings so your team can spend its time on confirmed threats rather than alert volume. Findings that are evaluated as benign are archived automatically, the ones that need a response become proactive cases, and posture issues stay in Current for your team to handle.

Cases show only a small part of that work. When I deliver AWS Security Incident Response to customers now, I walk them through the triage flow in Figure 1, the Proactive response dashboard, and their monthly report, so they can see how triage works end to end.

To get started, see the onboarding guide. Setup takes about 10 minutes. For more information, see the AWS Security Incident Response product page or the User Guide.

If you have questions about this post, contact AWS Support or start a new thread on AWS re:Post.


Anatoliy Kochetov

Anatoliy Kochetov

Anatoliy is a Technical Account Manager and AWS Security Incident Response SME. He works with AWS Enterprise customers, providing ongoing support and technical guidance to help them build secure, resilient solutions using AWS best practices.

AWS Lambda Durable Functions observability with OpenTelemetry

Post Syndicated from Ricardo Marques original https://aws.amazon.com/blogs/compute/aws-lambda-durable-functions-observability-with-opentelemetry/

Gaining observability into AWS Lambda Durable Functions, a capability of AWS Lambda, can be challenging. A single workflow can span multiple invocations, queues, and downstream services, with no persistent host or centralized log file to inspect. With OpenTelemetry, you can close that gap by generating and correlating traces, metrics, and logs through an open specification. You can instrument once and export anywhere, which avoids vendor lock-in and establishes a baseline for operating serverless systems at scale.

With AWS Lambda Durable Functions, you can construct resilient workflows with multiple steps, which save their state and automatically recover from errors by replaying. A single durable execution can persist across several Lambda calls. It can continue after pauses, recover from errors, and restart from saved checkpoints. Although this model delivers fault tolerance, it introduces an observability challenge. Each invocation generates its own trace, fragmenting the end-to-end view of a single logical workflow.

This post introduces the OpenTelemetry plugin for the AWS Durable Execution SDK (aws-durable-execution-sdk-python-otel). With this plugin, you can generate deterministic trace IDs that unify all invocations of a single durable execution into one coherent distributed trace. In this post, you learn how to set up the plugin, see the traces it produces for the happy-path workflow, and apply foundational best practices.

The complete application code is available in our GitHub repository, so this post uses code snippets to illustrate the examples.

The problem: fragmented traces across invocations

Consider a document review workflow with a human approval gate:

import json

from aws_durable_execution_sdk_python import (
    DurableContext,
    durable_execution,
    durable_step,
)
from aws_durable_execution_sdk_python.types import WaitForCallbackContext


@durable_step
def extract_text(step_context, doc_id):
    step_context.logger.info(f"Extracting text from document: {doc_id}")
    return {"doc_id": doc_id, "text": "extracted content"}


@durable_step
def summarize(step_context, extracted):
    step_context.logger.info(f"Summarizing document: {extracted['doc_id']}")
    return {"summary": "Document summary here"}


@durable_step
def publish(step_context, summary, approval):
    step_context.logger.info(f"Publishing with approval from: {approval.get('reviewer')}")
    return {"status": "published"}


@durable_execution
def handler(event: dict, context: DurableContext) -> dict:
    extracted = context.step(extract_text(event["doc_id"]), name="extract-text")
    summary = context.step(summarize(extracted), name="summarize")

    def submit_for_review(callback_id: str, ctx: WaitForCallbackContext) -> None:
        notify_reviewer(callback_id, summary)

    approval = context.wait_for_callback(submitter=submit_for_review, name="human-review")
    if isinstance(approval, str):
        approval = json.loads(approval)

    if not approval.get("approved"):
        return {"status": "rejected", "reason": approval.get("feedback")}

    context.step(publish(summary, approval), name="publish")
    return {"status": "published"}

This workflow runs across at least two Lambda invocations. The first invocation executes extract-text and summarize, then suspends at human-review with zero compute cost while waiting. Hours later, when the reviewer responds, Lambda invokes the function again. It replays the completed steps and executes publish.

The following diagram illustrates the difference between the default behavior and the plugin’s unified tracing. On the left side, two independent traces are generated: Trace A captures the first invocation (totaling 2.69 seconds), while Trace B captures the second invocation after the callback resumes (replaying and publishing in 0.37 seconds). These traces have different trace IDs and no correlation between them. On the right side, with the OTel plugin, all operations appear under a single deterministic trace ID. The human-review wait (6 hours and 8 minutes at zero compute cost) is represented as a continuous span connecting both invocations, giving operators a complete timeline from start to finish. You can compare the total wall-clock duration of 152 seconds against only 0.019 seconds of actual compute time billed.

Figure 1. race comparison of fragmented traces without the plugin (left) versus a single unified trace with the OTel plugin.

Figure 1. Trace comparison of fragmented traces without the plugin (left) versus a single unified trace with the OTel plugin (right), showing how the Durable Execution SDK merges multiple Lambda invocations into one end-to-end trace.

The plugin achieves this through:

Capability What it does
Deterministic trace IDs Derives a stable trace ID from the AWS X-Ray header, so all invocations share one trace
Span-per-operation Each step, wait, or wait_for_callback gets its own span with real timing
Continuation spans Operations completing in a later invocation link back to the original span
Log correlation Stamps traceId and spanId onto every log record automatically
Configurable sampling Standard OpenTelemetry sampling to control trace volume
Figure 2. Amazon CloudWatch Application Signals Traces view. The durable execution appears as a single trace with OK status. The Duration column (152s) reflects the total wall-clock time including the human-review wait, while Response Time (0.019s) shows only the compute time.

Figure 2. Amazon CloudWatch Application Signals Traces view. The durable execution appears as a single trace with OK status. The Duration column (152s) reflects the total wall-clock time including the human-review wait, while Response Time (0.019s) shows only the compute time.

Choose execution view to see all operations grouped under the Workflow span. Use this view when the full execution, including waits and retries, finishes within your tracing vendor’s span ingestion window. For example, if your vendor rejects spans that started more than 8 hours ago, use execution view only for workflows that reliably finish well under 8 hours.Choose invocation view if an execution might exceed your vendor’s ingestion window, or if you want to see progress as each function execution terminates. Operations appear under the invocation that ran them. A wait’s first segment appears under the invocation that started it, even while the wait is still pending.In both views, the Workflow span covers the full execution, so the vendor’s ingestion window still applies to it. If an execution runs longer than the window, your vendor might reject the Workflow span even in invocation view.

The plugin sends Workflow as one span when the execution succeeds or fail. It doesn’t send that span in pieces. The vendor can, however, accept earlier spans from the same trace.

Why do we recommend someone to use invocation view for long running ones?Suppose a workflow waits 10 hours and the vendor rejects spans that started more than 8 hours ago. In invocation view, the invocation that starts the wait can export the wait’s initial span before the wait finishes. The invocation that resumes the workflow can later export the wait’s completion span. Those short spans can be accepted even if the vendor rejects the final Workflow span.

Getting started

In the following walkthrough, you configure your Lambda durable function to trace requests end-to-end.

Prerequisites

  • Python 3.11 or later.
  • An existing Lambda durable function (or a new one you want to instrument).
  • An AWS account with permissions to enable Amazon CloudWatch Application Signals tracing and add Lambda layers.

Step 1: Install the plugin

Add the plugin to your function’s dependencies:

pip install aws-durable-execution-sdk-python-otel

Or in your requirements.txt:

aws-durable-execution-sdk-python==3.0.2 
aws-durable-execution-sdk-python-otel==2.1.0

Step 2: Add the ADOT Lambda layer

With the AWS Distro for OpenTelemetry (ADOT) Lambda layer, you can export traces from your function.

MyDurableFunction:
  Type: AWS::Serverless::Function
  Properties:
    Runtime: python3.13
    Handler: index.handler
    Architectures:
      - x86_64
    DurableConfig:
      ExecutionTimeout: 31622400
    Layers:
      - !Sub arn:aws:lambda:us-east-1:615299751070:layer:AWSOpenTelemetryDistroPython:33
    Environment:
      Variables:
        AWS_LAMBDA_EXEC_WRAPPER: /opt/otel-instrument

Note: The examples in this post use AWS Serverless Application Model (AWS SAM) for brevity. You can achieve the same configuration using the AWS Command Line Interface (AWS CLI), AWS Cloud Development Kit (AWS CDK), Terraform, or AWS CloudFormation directly. Refer to the ADOT Lambda Layer ARNs page for the latest layer version and supported architectures. Pin the layer version in production deployments to avoid unexpected behavior from automatic version changes.

Step 3: Turn on X-Ray active tracing

The plugin uses the _X_AMZN_TRACE_ID environment variable to derive deterministic trace IDs. Turn on active tracing on your function:

MyDurableFunction:
  Type: AWS::Serverless::Function
  Properties:
    Tracing: Active

Also verify your function’s execution role includes the AWSXRayDaemonWriteAccess managed policy (or equivalent xray:PutTraceSegments and xray:PutTelemetryRecords permissions).

Step 4: Add the OTel plugin to your handler

Import InvocationOtelPlugin and pass it to the plugins parameter of @durable_execution:

from aws_durable_execution_sdk_python import DurableContext, durable_execution
from aws_durable_execution_sdk_python.config import Duration
from aws_durable_execution_sdk_python_otel import create_otel_plugin_factory
@durable_execution(plugins=[create_otel_plugin_factory()])
def handler(event: dict, context: DurableContext) -> str:
    data = context.step(lambda ctx: event["id"], name="fetch-data")
    context.wait(Duration.from_seconds(5), name="cooldown")
    return context.step(lambda ctx: f"processed {data}", name="process")

The plugin handles Tracer Provider setup, deterministic ID generation, and span lifecycle internally.

Testing and results

After you configure the plugin, deploy the function, invoke it, and confirm the unified trace appears in Amazon CloudWatch.

Testing the setup

Build and deploy your function:

sam build
sam deploy --guided

Then publish a function version (durable functions require a qualified ARN, not $LATEST):

aws lambda publish-version --function-name my-durable-function --region us-east-1

Invoke the function asynchronously (required when using wait_for_callback, since the function suspends mid-execution):

aws lambda invoke \
    --function-name my-durable-function \
    --qualifier 1 \
    --invocation-type Event \
    --region us-east-1 \
    --cli-binary-format raw-in-base64-out \
    --payload '{"doc_id": "test-doc-001"}' \
    response.json

Monitor the logs to get the callback ID:

aws logs tail /aws/lambda/my-durable-function --follow --region us-east-1

Wait 2-3 minutes (so the human-review span has visible duration in the trace), then send the callback:

aws lambda send-durable-execution-callback-success \
    --cli-binary-format raw-in-base64-out \
    --callback-id "<CALLBACK_ID_FROM_LOGS>" \
    --region us-east-1 \
    --result '{"approved": true, "reviewer": "alice"}'

Note: The send-durable-execution-callback-success command does not require --function-name. The callback ID already contains the reference to the execution.

What you see in Amazon CloudWatch Application Signals

After you invoke this function, open the Amazon CloudWatch console and choose Application Signals (APM), then Traces. You see a single unified trace containing:

  1. One root span representing the entire durable execution.
  2. Child spans for each named operation: extract-text, summarize, human-review, and publish.
  3. Accurate timing: each span reflects the actual wall-clock time of the operation, not replay time.
  4. Continuation links: if human-review completes in a different invocation (after the reviewer approves hours later), the span is linked back to the original trace.
Figure 3. Trace details view. The service map shows the flow: Client to Lambda Context (first invocation), then Lambda Function (second invocation after callback resume). Both invocations appear under a single trace ID with total duration of 4.55 sec.

Figure 3. Trace details view. The service map shows the flow: Client to Lambda Context (first invocation), then Lambda Function (second invocation after callback resume). Both invocations appear under a single trace ID with total duration of 4.55 sec.

Correlated logs

Because the plugin sets enrich_logger=True by default, your application logs are automatically stamped with traceId and spanId.

Figure 4. Expanded log entry in CloudWatch. Each log record includes traceId, spanId, and otelTraceSampled: true, which lets you correlate logs across all invocations of the same execution.

Figure 4. Expanded log entry in CloudWatch. Each log record includes traceId, spanId, and otelTraceSampled set to true, which lets you correlate logs across all invocations of the same execution.

You can combine the plugin’s log correlation with structured JSON logging to run powerful queries in Amazon CloudWatch Logs Insights:

fields @timestamp, @message, traceId, spanId
| filter traceId = "abcd1234567890abcdef1234567890ab"
| sort @timestamp asc

This returns logs from all invocations in chronological order, correlated to their respective spans.

Best practices

When you run the OTel plugin in production, keep the following performance, operational, and cost considerations in mind.

Performance considerations

  • Cold start impact: The ADOT layer adds overhead to cold starts and memory consumption. Measure the impact for your workload using Lambda Power Tuning. For latency-sensitive functions, consider using provisioned concurrency to keep warm environments available.
  • Memory overhead: The plugin and ADOT layer consume approximately 40–60 MB of additional memory. Verify your function has sufficient memory allocated.
  • Replay efficiency: During replay, the plugin correctly identifies replayed operations and does not emit duplicate spans. Only new operations generate new spans.

Operational guidelines

  • Name your operations: Always pass the name parameter to context.step(), context.wait_for_callback(), and other durable operations. These names appear as span names in your traces, making them human-readable.
  • Use structured logging: Combine the plugin’s log correlation with structured JSON logging to unlock powerful Amazon CloudWatch Logs Insights queries.
  • Monitor trace gaps: If you see traces with missing spans, check that X-Ray active tracing is enabled and the ADOT layer is correctly configured.

Cost management

  • Amazon CloudWatch Application Signals pricing: You are charged per trace recorded and per trace scanned. At high volumes, configure sampling to control costs. See Amazon CloudWatch Application Signals pricing.
  • Log volume: With enrich_logger=True, every log record includes trace context fields, slightly increasing log volume. This overhead is typically negligible but worth noting for high-throughput functions.

Pricing

The plugin is open source (Apache 2.0). Costs come from AWS X-Ray traces recorded and the ADOT Lambda layer overhead. The layer increases both the memory consumption and the cold start duration of your function. Lambda pricing is based on GB-seconds, so the additional memory allocated (rounded up to the nearest MB) multiplied by the additional execution time per invocation determines the cost impact. Each durable execution produces one trace regardless of invocation count, so X-Ray cost scales with executions, not invocations. Measure the overhead for your workload using Lambda Power Tuning and see AWS X-Ray pricing for current rates.

Beyond this post

This post focused on a single, representative workflow (sequential steps plus a human-approval callback) to keep the walkthrough concrete. It is not an exhaustive tour of the SDK. The Durable Execution SDK offers many other primitives that also produce spans and are worth exploring: durable timers (context.wait), condition polling (context.wait_for_condition), durable Lambda-to-Lambda calls (context.invoke), parallel and fan-out execution (context.parallel, context.map), nested child contexts, and automatic retries (with_retry and StepConfig), where each attempt and each parallel branch surfaces as its own span. We also did not cover failure paths, such as step errors and failure callbacks, which is where unified tracing is often most valuable.

Likewise, the OTel plugin exposes configuration we did not exercise here: toggling log enrichment (InvocationOtelPlugin(OtelPluginConfig(enrich_logger=False))), supplying a custom Tracer Provider via OtelPluginConfig(tracer_provider=...), and controlling trace volume through standard OpenTelemetry sampling (OTEL_TRACES_SAMPLER). This walkthrough sampled 100% of traces. Consult the SDK documentation for the full surface area, or access the GitHub repository.

Sending Lambda durable functions traces to Observability partners. The OpenTelemetry plugin exports telemetry data to Amazon CloudWatch and can work with any observability solution that supports OpenTelemetry. Dash0 is an OpenTelemetry-native observability platform that supports Lambda durable functions without custom configuration. Dash0 worked with AWS to validate the OpenTelemetry plugin for the AWS Durable Execution SDK for JavaScript prior to launch, Dash0 coordinates logs and spans. In Dash0, spans for the durable execution, each invocation, and each durable operation appear alongside the function’s inputs and outputs and the payloads of its AWS SDK calls. To learn more, visit About AWS Lambda Monitoring.

Clean up

To avoid ongoing charges, delete the resources created in this walkthrough:

sam delete --stack-name <your-stack-name>

This removes the Lambda function, AWS Identity and Access Management (IAM) roles, and any associated resources created by the SAM template.

If you manually added the ADOT Lambda layer or X-Ray tracing policies outside of your SAM template, remove those separately using the AWS CLI or console.

Trace data retained in X-Ray does not incur storage charges and expires automatically after 30 days.

Conclusion

In this post, we showed how to unify fragmented traces across multiple Lambda invocations using the OpenTelemetry plugin for the Durable Execution SDK. To explore the full SDK surface area, including parallel execution, durable timers, and failure-path tracing, see the AWS Durable Execution SDK Developer Guide. For more observability patterns, visit the AWS Observability Best Practices guide.

How Moonfrog scales analytics and lowers query cost with Amazon Redshift RG instances

Post Syndicated from Anirudh Chawla original https://aws.amazon.com/blogs/big-data/how-moonfrog-scales-analytics-and-lowers-query-cost-with-amazon-redshift-rg-instances/

Moonfrog Labs uses Amazon Redshift to analyze mobile game telemetry. Each session, purchase, and player drop-off generates events that product and analytics teams use to understand game performance. Faster loading and querying help those teams work with fresher data.

Moonfrog runs a single production analytics cluster with roughly 148 TB in Amazon Redshift Managed Storage (RMS) and about 4,000 warehouse tables. It also queries roughly 1,000 external data lake tables. The warehouse supports telemetry ingestion, revenue reporting, marketing attribution, and self-service dashboards for product, data science, analytics, and support teams.

In this post, we show how Moonfrog migrated its production analytics warehouse from Amazon Redshift RA3 to RG instances using elastic resize. We explain how the team selected capacity for growing analytics demand and more frequent loading, verified warehouse and data lake access, and assessed performance and costs after migration.

The challenge

Moonfrog’s RA3 cluster ran reliably, with no stability issues. Its constraint was compute headroom as analytics demand grew. Ingestion volume was steady before migration. Growth came from analytical queries and data lake scans. The team already planned to expand from five RA3 nodes to six or seven nodes and wanted capacity to load warehouse data more frequently.

The five-node ra3.4xlarge cluster averaged about 54% CPU utilization. In approximately 98% of hours, CPU peaked at or above 90%. Other indicators showed demand increasing:

  • SELECT queries per day increased 31% from January to July.
  • Mean workload management (WLM) queue wait for highest-priority queries rose from 505 milliseconds in May to 940.7 milliseconds in July.
  • Concurrency scaling usage nearly doubled over the same period, from 4,453 to 8,516 seconds per day.

A COPY operation averaged 16.8 seconds on RA3. That duration constrained how often the stats pipeline could load. The team evaluated RG as a way to support growing analytics demand and make more frequent loads practical.

Moonfrog also queried roughly 1,000 external tables in Amazon Simple Storage Service (Amazon S3). Data scanned through Redshift Spectrum increased 33%, from 84.9 TB in March to 112.5 TB in June. The separate Spectrum scanning charge added to the cost of expanding RA3 compute.

Moonfrog used WLM query monitoring rules to stop scans larger than one terabyte. These rules controlled scan spend under the RA3 configuration.

The one-year no-upfront reserved node commitment for ra3.4xlarge expired in July 2026. Renewal gave Moonfrog an opportunity to re-evaluate its compute commitment and determine whether switching to RG would provide additional headroom for its growing workload needs.

Solution overview

Amazon Redshift RG instances use AWS Graviton processors and an integrated data lake query engine. AWS publishes benchmarks of up to 2.2 times faster warehouse workloads and up to 2.4 times faster Apache Iceberg workloads, at 30% lower price per vCPU than RA3. These benchmarks are separate from Moonfrog’s production results. RG runs Apache Iceberg and Apache Parquet scans on cluster nodes, removing the separate per-terabyte Spectrum charge for these scans. Elastic resize supports changing the node family and capacity without a customer-managed export and reload.

Moonfrog retained its ingestion and analytics architecture at cutover. No service was added or removed, and applications continued to use the same warehouse.

The following diagram illustrates the architecture.

Architecture: ingestion writes files to Amazon S3, COPY loads Redshift warehouse tables, and the RG data lake engine queries external S3 tables in place

Figure 1: The ingestion pipeline writes columnar files to Amazon S3. COPY loads warehouse tables, and the integrated data lake engine on RG queries external tables in place. Conversational analytics is a planned use of the additional headroom

The architecture uses the following AWS services:

Implementation steps

Moonfrog established a baseline, used elastic resize to change the node family, and verified warehouse and data lake access. It then evaluated the early results before selecting its final configuration.

Step 1: Establish a baseline

Before the change, the team captured Amazon CloudWatch metrics for CPU utilization, WLM queue wait by priority, query duration by type, and queries per day. COPY loads and SELECT queries were measured separately. Billing records provided reserved compute, Spectrum scanning, and concurrency scaling costs so the comparison covered each billing line affected by the move.

AWS provides migration planning and workload validation guidance in the AWS RA3 to RG best practices blog.

Step 2: Validate the target configuration and use elastic resize

AWS recommends testing the target RG configuration in a non-production environment with representative workloads before migrating production. That testing is intended to measure benefits, identify issues, and validate the target size before the production migration.

On 26 July, Moonfrog used elastic resize to move from five ra3.4xlarge nodes to eight rg.4xlarge nodes, temporarily providing extra capacity to reduce migration risk. It did not export or reload the 148 TB warehouse. Schemas, ETL jobs, application SQL, drivers, connection strings, and BI tools continued to work.

Amazon CloudWatch recorded one five-minute interval in which the cluster reported unhealthy. Database connections recovered immediately afterward. This sampling interval describes the observed impact. It does not establish an exact five-minute outage duration.

AWS guidance describes elastic resize as a short operation, typically about 10 to 15 minutes. After an RA3-to-RG node-type change, data hydration brings frequently accessed data from managed storage into the new nodes’ local cache. This cache warming should be considered when interpreting early performance measurements.

Step 3: Verify warehouse and data lake access

Moonfrog verified that warehouse loads and external queries continued after the resize. External schemas and tables remained in use, with AWS Glue Data Catalog providing their metadata.

Moonfrog confirmed that per-terabyte S3 scanning charges were eliminated for its RG queries in the subsequent billing records. Those queries used provisioned cluster capacity, which remained billable.

Step 4: Review workload management rules

Moonfrog’s Auto WLM configuration included separate queues for administrators, analysts, ETL, loading, and visualization, along with short query acceleration. These queues carried across the migration. The team reviewed query monitoring rules because data lake scans now consumed RG cluster capacity.

The review accounted for data lake scans sharing compute with warehouse workloads. Rules that previously controlled scan spend could still protect these shared resources.

Results and key benefits

The following four CloudWatch charts cover 1 May to 25 October 2026. Each marks the 26 July resize and shades the 26 July–3 August period when the cluster was reduced from eight to seven to six RG nodes. Query duration and WLM wait charts show seven-day rolling means. Query counts include COPY, SELECT, INSERT, utility, and other operations.

Stage 1: Evaluate RG after cutover

The first evaluation focused on workload continuity and query runtime. Warehouse loads and data lake queries continued, and the applications used the same schemas, SQL, drivers, and connection strings. Queries on the initial RG configuration were completing within expected runtimes. Moonfrog then reduced the node count in stages to assess whether each reduction affected query runtime.

The cleanest comparison of COPY duration is 27–31 July, when load volume remained unchanged. Mean duration fell from 16.8 seconds on RA3 to 3.6 seconds on RG, about 79% shorter. This window falls within the 26 July–3 August right-sizing period, before the final six-node configuration was established.

Select six nodes

Moonfrog reduced the cluster from eight to seven and then six RG nodes within eight days. The team retained the additional node relative to its five-node RA3 baseline to support growing analytical demand and more frequent loading. It had already planned to expand RA3 to six or seven nodes.

The move from five RA3 nodes to six RG nodes increased node count by 20%. Published node specifications list 12 vCPUs per ra3.4xlarge and 16 per rg.4xlarge, so provisioned vCPUs increased from 60 to 96, or 60%. The results reflect the change in both node family and capacity.

Stage 2: Sustain performance as workloads grow

After validating the available headroom on the six-node configuration, Moonfrog increased loading frequency on 24 August. The cluster now executes more than 70,000 COPY operations a day, about 4.3 times the RA3 baseline. These loads use smaller, more frequent batches, so later COPY duration also reflects the changed loading pattern. Figure 2 shows the early duration improvement and subsequent performance as the workload changed.

In late August, after the 24 August increase in loading frequency, Moonfrog purchased a one-year no-upfront reservation for the six-node RG configuration. The purchase followed its evaluation of RG with production traffic and committed capacity for anticipated workload growth.

Customer CloudWatch chart of seven-day rolling mean COPY and SELECT duration from May to 25 October 2026. Resize on 26 July and right-sizing through 3 August.

Figure 2: Mean COPY and SELECT duration. The early COPY comparison uses unchanged volume. Later means also reflect smaller batches after 24 August

More daily queries with compute headroom

Daily queries across all types increased from around 49,122 on RA3 to 83,603 in August, 125,350 in September, and 125,374 during 1–25 October. From September onward, this was more than 2.5 times the RA3 baseline. COPY accounts for much of that increase, so total query growth should be read alongside the query mix in Figure 3.

Customer CloudWatch stacked-area chart of successful COPY, SELECT, utility, INSERT, and other queries per day, showing the increase in COPY frequency on 24 August.

Figure 3: Successful daily queries by type. COPY frequency increased on 24 August, after the migration and right-sizing period

Concurrency scaling remained enabled to absorb peak bursts alongside the six reserved nodes. Average daily usage was 14–29% below the RA3 baseline in August, September, and October, even as total query volume grew. Usage increased from September to October as demand rose.

Average CPU utilization fell from about 54% on RA3 to 35–39% from September onward, despite the higher query count. Figure 4 distinguishes daily average CPU from the typical peak, defined as the daily mean of each hour’s maximum CPU reading.

Customer CloudWatch chart of daily average CPU and the daily mean of hourly maximum CPU readings. Average utilization falls after the 26 July resize.

Figure 4: CPU utilization before and after the resize. The typical peak is an average of hourly maximum readings, not the single daily maximum

Queue waits as demand grows

Queue waits fell after migration and rose from their August lows as traffic increased in October. During 1–25 October, highest-priority waits averaged 561 milliseconds versus a July RA3 baseline of 940.7 milliseconds, and high-priority waits averaged 193 milliseconds versus 294 milliseconds. Normal-priority waits were about 11 milliseconds, above their July baseline of about 3.6 milliseconds. Figure 5 uses a separate vertical scale for each priority.

Customer CloudWatch chart with highest, high, and normal priority panels. Highest and high priority mean waits remain below their RA3 July baselines in October. Normal priority waits rise.

Figure 5: Seven-day rolling mean WLM queue wait by priority. Dashed lines mark July RA3 baselines. Each panel has its own scale

Integrated data lake queries and billing

External data lake queries continued after migration. Moonfrog confirmed that the separate Spectrum scanning charge remained exactly $0 from 27 July through the reported months:

  • The Amazon Redshift system views showed that external queries continued. A recent three-day sample recorded roughly 200,000 external queries against Amazon S3, including Parquet scans. External schemas and tables remained in use.
  • Billing records showed no separate per-terabyte scanning charge. External scans use provisioned RG capacity, which remains billable. Amazon S3 storage and other charges are outside this comparison.

Cost per query

Moonfrog chose additional capacity for growth, and monthly spend across reserved compute, Spectrum scanning, and concurrency scaling increased approximately 4–6%. On a consistent 30-day basis, cost per 1,000 total queries fell approximately 59% in September and 58% in October. Costs per 1,000 SELECT queries fell 38–50% across August through October.

Metric RA3 × 5
Before
RG × 6
August
RG × 6
September
RG × 6
Oct 1–25
Queries per day All types 49,122 83,603 125,350 125,374
Cost per 1,000 total queries $5.60 $3.45 −38% $2.28 −59% $2.33 −58%
Reported cost per 1,000 SELECT $45.60 $22.73 −50% $25.19 −45% $28.34 −38%

Cost per 1,000 total queries is calculated by dividing the combined 30-day spend for reserved compute, Spectrum scanning, and concurrency scaling by 30 times the average daily query count, then multiplying by 1,000. These are aggregate cost measures, not the execution cost of an individual query.

How the team plans to use the headroom

The larger configuration created room to test additional analytical use cases. Earlier measurements showed mean short-query duration falling from about 2.8 seconds to 1.8 seconds. That observation applies to the measured short-query workload and does not establish a response-time guarantee for every analytical question.

Moonfrog plans to evaluate conversational analytics using large language model (LLM) agents. Such agents may execute several queries to answer one question, so query latency is one part of the end-to-end response time. The additional compute headroom gives the team room to test these workloads alongside existing analytics.

Lessons learned

  • Use a reserved node renewal as an opportunity to review capacity and architecture for your growing workload needs. Moonfrog evaluated RG before making another one-year commitment.
  • Size the cluster for expected workload growth and assess results against the capacity provisioned. Moonfrog added a sixth node for headroom. Interpret total query counts alongside the query mix, because smaller, more frequent COPY batches increase the number of operations.
  • Include concurrency scaling in capacity planning. In this deployment it continued to absorb peak bursts alongside the reserved nodes, so evaluate its contribution when assessing warehouse throughput.
  • Separate immediate migration results from subsequent workload changes. The unchanged-volume COPY comparison captures the first days after cutover. Later results include the loading cadence change and rising demand. Measure dashboard latency and query abandonment separately to quantify the effect on users.

Next steps

Moonfrog has already increased warehouse loading frequency. The team plans to measure dashboard load times and query abandonment to assess how greater freshness and shorter query durations affect the experience of product and analytics teams.

Moonfrog is considering Apache Iceberg for data lake tables currently stored as Parquet files. The table format would add capabilities such as schema evolution and time travel. The team will evaluate these changes alongside performance and operating requirements.

The team also plans to evaluate broader natural language access. Governance must define which teams can access each table and how exploratory queries share cluster resources. End-to-end agent response time will need separate measurement.

Conclusion

Moonfrog migrated its 148 TB production Amazon Redshift warehouse from five RA3 nodes to RG using elastic resize, then settled on six nodes after eight days of measured right-sizing. RA3 had run reliably. The change addressed growing analytics demand and the need for more frequent warehouse loads. COPY duration fell from 16.8 seconds to 3.6 seconds at unchanged volume immediately after cutover.

With six RG nodes, Moonfrog handled more than 125,000 daily queries across all types from September onward, over 2.5 times the RA3 baseline. Average CPU utilization was 35–39%. More frequent COPY batches contributed to the change in query mix. External queries continued with no separate Spectrum scanning charge, and concurrency scaling provided burst capacity alongside the reserved nodes.

To evaluate RG for your warehouse, review Amazon Redshift pricing, the elastic resize documentation, and the RA3 to RG migration best practices. Establish a baseline and test representative workloads in a non-production environment first. Validate warehouse and data lake access, then compare total spend and cost per unit of work before committing to reserved capacity.


About the authors

Anirudh Chawla

Anirudh Chawla

Anirudh is an Analytics Solution Architect at AWS. He helps organizations harness their data effectively through AWS analytics solutions. His interests include building highly available distributed systems.

Poornima Bansal

Poornima Bansal

Poornima is a Senior Account Executive at Amazon Web Services (AWS) based in Bengaluru, India. She leads cloud and generative AI engagements with digitally native businesses. She is passionate about helping organizations harness AI and emerging technologies to drive innovation.

Sathish Balaji

Sathish Balaji

Sathish is an Analytics Specialist at Amazon Web Services. He focuses on building strong data foundations that enable analytics and AI. Outside work, he enjoys travelling and experiencing new cultures.

Monazir Hussain

Md Monazir Hussain

Monazir is a Senior Software Engineer at Moonfrog Labs, specializing in data platforms, cloud infrastructure, and distributed systems. He works on designing and scaling backend and data systems that power large-scale mobile games. He is passionate about solving complex scalability challenges, improving system reliability, and using automation and AI to simplify engineering and operational workflows.

Raunshan Kumar

Raushan Kumar

Raushan is a DevOps Engineer 2 working on cloud infrastructure and data platforms at Moonfrog. He specializes in designing, automating, and optimizing AWS infrastructure, with expertise spanning Kubernetes, CI/CD pipelines, infrastructure as code, and Amazon Redshift. He focuses on improving reliability, scalability, performance, and cost efficiency across Moonfrog’s gaming and analytics workloads.

Monitor the efficiency and availability of accelerated computing instances with Amazon EC2 Detailed Monitoring and performance status checks

Post Syndicated from Caroline Frost original https://aws.amazon.com/blogs/compute/monitor-the-efficiency-and-availability-of-accelerated-computing-instances-with-amazon-ec2-detailed-monitoring-and-performance-status-checks/

Amazon Elastic Compute Cloud (Amazon EC2) accelerated computing instances run some of the most demanding workloads customers operate, from large model training and distributed fine-tuning to high-throughput, live inference. These customers seek high availability and performance to make sure their training and inference run efficiently. To meet their performance goals, customers require visibility into the efficiency and performance of each accelerated computing chip in their fleet.

For example, central infrastructure or machine learning teams often operate accelerated computing capacity for many application teams. These infrastructure teams need a clear view of utilization and health across every instance in their fleet even if they don’t develop the applications running on those instances. They are often responsible for how efficiently that capacity is used and for hardware health, while application teams own the workload. Customers asked us to provide foundational telemetry for their accelerated computing efficiency and status that doesn’t require setup within the instance and complements their in-guest tooling.

Amazon EC2 now reports one-minute graphics processing unit (GPU) metrics through Detailed Monitoring and surfaces recoverable conditions with performance status checks. One-minute GPU metrics in Amazon EC2 Detailed Monitoring report per-GPU utilization and thermal data to Amazon CloudWatch, so you can identify underused capacity and tune workloads for cost and throughput. Performance status checks report recoverable hardware conditions, such as a GPU memory error, to help you manage GPU performance.

Feature overviews

Amazon EC2 reports GPU metrics and performance status checks without an in-guest agent and without using instance compute. These capabilities are available on supported NVIDIA GPU-based accelerated computing instance types. For the metrics supported on each instance family, see the Amazon EC2 Detailed Monitoring documentation.

One-minute accelerated computing metrics extend EC2 Detailed Monitoring and are published to CloudWatch as OpenTelemetry Metrics or CloudWatch Metrics. The metric name you add to a category determines which one CloudWatch publishes: include GPUUtilization for a CloudWatch Metric, instance.gpu.utilization for an OpenTelemetry Metric, or both names to publish both. Amazon EC2 publishes each metric to CloudWatch at two levels: one series for the instance, identified by InstanceId, and one series for each GPU, identified by InstanceId and GpuId. GpuId is the GPU UUID, which you can match to a device by running nvidia-smi -L on the instance.

Performance status checks add a fifth status check to the existing Amazon EC2 product check suite of system, instance, attached EBS, and application status checks. The check reports recoverable hardware issues that affect accelerated computing performance while the instance might remain running and reachable. It surfaces through the EC2 console, through DescribeInstanceStatus, and in CloudWatch metrics.

Evaluating accelerated computing utilization and performance with EC2 Detailed Monitoring

Amazon EC2 Detailed Monitoring reports per-GPU measurements, including compute activity, memory use, temperature, and data movement.

GPU utilization metrics report different aspects of GPU use. GPUPowerUtilization is available by default and reports active power use. Power utilization scales with the depth of work the GPU performs. Compare it with more granular utilization metrics to see how efficiently your workload uses the GPUs. GPU utilization shows the percentage of time the GPU was running work. Because a busy GPU might use only a fraction of its streaming multiprocessors (SMs), compare it with SM utilization to see how much of the compute capacity the workload uses. Memory utilization shows how much of the GPU’s memory capacity is in use, helping you assess memory headroom. Context accumulated time is a running total of the time a process has held the GPU open, whether or not it ran work. Use the CloudWatch metric math expression RATE(m1)/1000000, where m1 is GPUContextAccumulatedTime, to compare context activity with GPU utilization. A result close to 1 with low GPU utilization indicates that a GPU context is held open but idle.

GPU temperature is reported as a percentage of the GPU’s thermal throttle limit, and memory temperature as a percentage of the memory’s critical temperature. Both metrics can report values above 100 percent when a GPU or its memory runs above the limit. A GPU reduces its clocks when it reaches its throttle limit, so a value at or above 100 percent can explain a drop in throughput. You can correlate these measurements with GPU and interconnect utilization metrics to understand workload performance.

Interconnect utilization metrics show how much of the available bandwidth a workload uses for data movement. Each value reports the busier direction, either send or receive. NVLink utilization measures GPU-to-GPU traffic, such as collective operations in distributed training. It reports all of the GPU’s links together. PCIe utilization measures traffic between the host and the GPU.

Getting started with EC2 Detailed Monitoring

Amazon EC2 Detailed Monitoring publishes instance metrics to Amazon CloudWatch at one-minute intervals without running an agent in the guest operating system. You can publish these as OpenTelemetry Metrics or CloudWatch Metrics.

To get started, create a metric category, an Amazon EC2 resource containing the metrics you want to collect. Next, associate the category with one or more instances. For an existing instance, provide the category ID when you enable Detailed Monitoring with the MonitorInstances API. For a new instance, provide the category ID in the Monitoring object when you call RunInstances or configure a launch template.

The following example creates a metric category for GPU utilization, SM utilization, and memory utilization.

aws ec2 create-metric-category --metrics instance.gpu.utilization instance.gpu.sm_utilization instance.gpu.memory_utilization

The response includes a metric category ID. To associate the category with an existing instance, use MonitorInstances.

aws ec2 monitor-instances --instance-ids <instance-id> --metric-category-ids <metric-category-id>

To associate the category when you launch an instance, include the category ID in the Monitoring object.

aws ec2 run-instances --image-id <ami-id> --instance-type <instance-type> --count 1 --monitoring Enabled=true,MetricCategoryIds=<metric-category-id>

To apply a category to every instance launched from a launch template, include the category ID in the Monitoring object in the launch template data.

aws ec2 create-launch-template --launch-template-name accelerated-computing-monitoring --launch-template-data '{"Monitoring":{"Enabled":true,"MetricCategoryIds":["<metric-category-id>"]}}'

Categories apply to many instances at once, unlike per-instance metric settings. Define the metric set once and associate it wherever it applies. Every associated instance then reports the same set of metrics. Changing a category updates the metric set for every associated instance. The change is eventually consistent across running instances. Add the category to a launch template to apply the same metrics to new instances. This gives you one metric definition per workload type instead of one configuration per host. Metrics apply under standard Amazon CloudWatch pricing.

Managing accelerated computing availability with performance status checks

Accelerated computing hardware can experience non-terminal issues that affect performance and can be resolved with a GPU reset or an instance reboot. For example, when a GPU encounters an uncorrectable memory error, it schedules a repair that remaps the affected row to a spare. The repair takes effect the next time the GPU is reset or the instance is rebooted.

Amazon EC2 performance status checks surface these recoverable hardware conditions. For example, when Amazon EC2 detects a pending GPU memory row remap, the instance’s performance status check reports an impaired status and identifies reboot as the recommended remediation.

You can view performance status checks on the Amazon EC2 console or through DescribeInstanceStatus. Amazon EC2 also publishes the StatusCheckFailed_Performance metric to CloudWatch. A failed performance status check also increments the combined StatusCheckFailed metric. The following example uses the EC2 DescribeInstanceStatus API:

aws ec2 describe-instance-status --instance-ids i-0123456789abcdef0

The following response shows the system, instance, attached EBS, and configured application status checks passing while the performance status check is impaired:

{
  "InstanceStatuses": [
    {
      "AvailabilityZone": "us-east-1a",
      "InstanceId": "i-0123456789abcdef0",
      "InstanceState": {
        "Code": 16,
        "Name": "running"
      },
      "InstanceStatus": {
        "Details": [
          {
            "Name": "reachability",
            "Status": "passed"
          }
        ],
        "Status": "ok"
      },
      "SystemStatus": {
        "Details": [
          {
            "Name": "reachability",
            "Status": "passed"
          }
        ],
        "Status": "ok"
      },
      "AttachedEbsStatus": {
        "Details": [
          {
            "Name": "reachability",
            "Status": "passed"
          }
        ],
        "Status": "ok"
      },
      "ApplicationStatus": {
        "Status": "ok"
      },
      "PerformanceStatus": {
        "Status": "impaired",
        "ImpairedSince": "2026-10-18T14:32:00Z",
        "Remediation": "reboot"
      }
    }
  ]
}

Amazon EC2 sends a scheduled event for the instance if the condition requires further action after a reboot.

To act on these conditions across your accelerated computing instances, create a CloudWatch alarm on StatusCheckFailed_Performance.

  1. The alarm on StatusCheckFailed_Performance fires for an instance in a training cluster.
  2. You confirm the condition and the recommended action with DescribeInstanceStatus, which returns a status of impaired and a remediation of reboot.
  3. You checkpoint the job if applicable, then drain the node and reboot the instance at a planned point. On Amazon Elastic Kubernetes Service (Amazon EKS), cordon and drain the node. In Slurm, set the node to DRAIN.
  4. After the reboot completes, the performance status check returns to ok.

The following command creates that alarm for a single instance.

aws cloudwatch put-metric-alarm --alarm-name performance-status-impaired-<instance-id> --namespace AWS/EC2 --metric-name StatusCheckFailed_Performance --dimensions Name=InstanceId,Value=<instance-id> --statistic Maximum --unit Count --period 60 --evaluation-periods 2 --threshold 1 --comparison-operator GreaterThanOrEqualToThreshold --alarm-actions <sns-topic-arn>

A CloudWatch Metrics Insights alarm evaluates a single query across all matching instances, so one alarm can cover a large fleet. To drive automation without an alarm, poll the DescribeInstanceStatus API.

Rebooting the instance is the recommended remediation. Alternatively, you can reset the affected GPU while keeping the other GPUs running. On the affected instance, run nvidia-smi -q -d ROW_REMAPPER and find the GPU that reports Pending: Yes. Stop all processes using that GPU, then use root permissions to run nvidia-smi -r -i <GPU_UUID>. The performance status check returns to ok shortly after the reset completes.

Bringing it all together

Accelerated computing metrics and performance status checks address complementary questions. Detailed Monitoring metrics help you find idle or underused capacity and tune workloads for cost and throughput. Performance status checks surface recoverable conditions and recommend remediation. Together, these EC2 signals report utilization and status across the capacity infrastructure teams manage, while in-guest tooling provides workload-specific analysis.

For example, a central infrastructure team monitors how efficiently workloads use the accelerated computing instances it manages for several application teams. It finds that one team’s GPUs report lower GPU utilization and power utilization than comparable workloads run by other teams. The infrastructure team shares the finding and relevant workload-tuning practices with the application team. After the application team updates that workload, the infrastructure team uses the same CloudWatch metrics to evaluate the change. The infrastructure team also monitors StatusCheckFailed_Performance across the fleet. When a check reports an impaired status and recommends a reboot, the orchestrator saves the active job, stops placing new work on the instance, and reboots it. After the check returns to ok, the orchestrator makes the instance available for new jobs. Together, these workflows help the team improve GPU utilization, protect job progress, and return affected capacity to service.

Amazon EC2 Detailed Monitoring reports accelerated computing metrics once per minute at the instance and GPU levels. Performance status checks report recoverable conditions at the instance level. Infrastructure teams can use these EC2 signals to monitor utilization and status across the capacity they manage. In-guest tools add process, container, Kubernetes pod, and sub-minute detail.

Amazon EC2 Detailed Monitoring reports metrics for your instances, including GPU utilization metrics reported per GPU. Performance status checks tell you when accelerated computing hardware needs attention. These capabilities help you evaluate utilization and manage the efficiency of your accelerated computing fleets. To learn more, see the Amazon EC2 Detailed Monitoring documentation and the EC2 status checks documentation.


About the author

Caroline Frost

Caroline Frost

Caroline is an Amazon EC2 Senior Product Manager – Technical, focusing on the EC2 instance lifecycle. She is passionate about building capabilities that improve the developer experience and create operational ease and simplicity.

The collective thoughts of the interwebz