Closing the AI agent trust gap with graduated autonomy

Post Syndicated from Dev Arora original https://aws.amazon.com/blogs/architecture/closing-the-ai-agent-trust-gap-with-graduated-autonomy/

How much to trust an AI agent is now a daily operational question. Agents read customer data, open tickets, process refunds, and delete accounts, yet most teams pick up a binary: full access or read-only. Full access is risky because agents fail unpredictably. Read-only leaves most of the agent’s value unused. The distance between what an agent could do and what an operator trusts it to do is the agent’s trust gap.

In this post, we describe graduated autonomy, an architectural pattern that closes the gap. Agents earn expanded permissions through sustained reliability and lose them when performance degrades. Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale with any framework or model, provides the runtime, gateway, policy, and evaluation capabilities. Amazon DynamoDB stores trust state. AWS CodePipeline gates delivery on evaluation results. We cover each layer’s responsibility and the key design decision behind it.

The agent trust gap

Identity and access management answers “who can do what?” once, at provisioning. That model assumes that the principal behaves consistently. A large language model agent breaks it: the same agent can be accurate Monday and hallucinated Tuesday after a prompt change or model update.

Closing the gap requires three capabilities raw API logs rarely provide:

  • Visibility. API logs tell engineers what happened but tell a compliance officer nothing about whether an action was safe.
  • Decision provenance. Tracing an action back to the signal that triggered it, the alternatives considered, and the confidence held.
  • Reversibility. Pre-action state capture, so operators can recover from incorrect actions.

The framework that implements this pattern delivers all three through six architectural layers.

Solution overview

The six layers:

  • Scoring engine computes trust from configurable dimensions.
  • Tier system translates sustained scores into autonomy levels.
  • Pre-execution layer blocks dangerous actions before they run.
  • Enforcement layer applies tiers through Cedar policies at the infrastructure level.
  • Post-execution layer evaluates outcomes, records of provenance, and feeds signals back to scoring.
  • Delivery gate keeps degraded agent versions out of production.
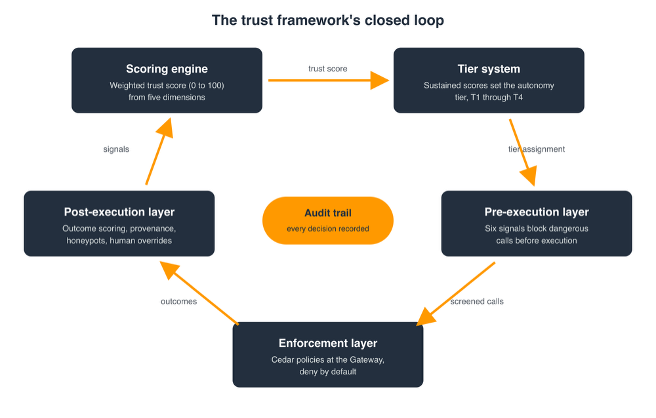
Architecture diagram of the trust framework as a clockwise closed loop: the scoring engine produces a weighted trust score from five dimensions, the tier system converts sustained scores into autonomy tiers T1 through T4, the pre-execution and enforcement layers apply the current tier through in-process checks and Cedar policies, and the post-execution layer returns outcome scores, honeypot results, and human overrides to the scoring engine, with an audit trail at the center recording every decision.

Figure 1: The trust framework’s closed loop.

Each layer is replaceable: the scoring model, tier thresholds, pre-execution signals, and evaluation criteria are configuration, not code. Each layer also embodies one deliberate design decision, developed in the following sections:

Layer Key design decision
Scoring engine Safety is an independent floor, never averaged away by strong metrics
Tier system Start every agent at T1. Promote slowly, demote immediately
Pre-execution layer Fast in-process filters are backstopped, never solely trusted
Enforcement layer Deny by default, enforced outside the agent’s process
Post-execution layer Audit records capture pre-action state, making recovery possible
Delivery gate One unauthorized tool call in adversarial tests blocks release

The scoring engine

The scoring engine computes a weighted score from 0 to 100 per agent over a rolling window of 50 actions, from five dimensions:

Dimension Weight What it measures
Accuracy 25% Task completion correctness against expected outcomes
Safety 20% Boundary respect, adversarial content detection, permitted tool adherence
Consistency 20% Behavioral predictability, inverse of tool-use pattern drift
Compliance 20% Reasoning quality before acting, guardrail adherence
Efficiency 15% Execution without unnecessary retries or resource waste

The composite drives dashboards and tier assignment, but safety acts as an independent floor, so a dangerous individual metric never hides strength elsewhere.

The tier system

Every new agent starts at T1, regardless of test performance:

Tier Score range Permissions
T1: Probation 0 to 40 Read and list only. Two tools visible.
T2: Supervised 41 to 70 Add write operations. Human approves high-risk.
T3: Trusted 71 to 90 Execute and modify. Anomalies flagged for review.
T4: Autonomous 91 to 100 Full access. Post-hoc audit only.

Three rules govern transitions:

  • Promotion requires sustained performance. The score must stay above the promotion threshold for the entire rolling window.
  • Demotion is immediate. When safety drops below its floor or injection is detected, the agent moves down.
  • Hysteresis prevents oscillation. Promotion into a tier requires a score 5 points above that tier range floor. Demotion happens at the range floor itself. An agent at a boundary cannot flap between tiers.

Trust state lives in Amazon DynamoDB as a current state record plus a time-series history per agent. Enforcement components read the current tier on every invocation, a lookup DynamoDB typically serves in single-digit milliseconds.

The pre-execution layer

Post-execution evaluation cannot undo damage, so the pre-execution layer evaluates every tool’s call and can block it before execution. It scores six signals independently:

  • Adversarial injection detection. Pattern matching against known injection phrases. One match triggers an instant block and a trust penalty.
  • Sensitive target detection. Regex matching credentials, tokens, and private keys in tool arguments.
  • Dangerous tool detection. Flagging tools that match destructive operation patterns.
  • Behavioral consistency. Comparing the current tool call against the agent’s historical tool-use distribution.
  • Confidence calibration. Comparing stated confidence against historical accuracy. Overconfident failures are penalized at twice the normal rate.
  • Reasoning quality. Checking whether the agent provided reasoning before acting.

These checks are fast first-pass filters, not a complete defense. The enforcement layer’s deny-by-default policies backstop anything they miss.

The enforcement layer

The pre-execution layer is application code inside the agent’s process. The enforcement layer operates outside the agent, at the infrastructure level.

AgentCore Gateway, a capability of Amazon Bedrock AgentCore, sits between the agent and its tools. It routes every MCP tool invocation through Policy in Amazon Bedrock AgentCore, which evaluates Cedar policies with forbid-wins semantics. One satisfied forbid overrides any number of permits. Tier maps to policy state:

  • Probation: A forbid policy blocks write, execute, and delete tool actions.
  • Promotion: The forbid policy is removed, and broader permits take effect.
  • Demotion: The forbid policy is re-applied.

With the policy engine in enforce mode, the Gateway lists only tools that policy could permit, so the tier’s unconditional forbids keep blocked tools out of the listing. The agent is unlikely to call a tool it has never seen. Listing is a meta-action: each invocation is still evaluated separately with full request context, including input parameters. Cedar denies by default. Enforcement never depends on the agent’s choosing to behave. For model-level content safety, Amazon Bedrock Guardrails complements Policy in AgentCore, filtering harmful content and masking sensitive information independent of tier.

The post-execution layer

After every tool call, the system scores the outcome across eight signals, from confidence calibration and behavioral drift to human overrides and retry detection. Every action generates an audit record following the Think, Plan, Act, Observe, Score chain:

  • Think: The agent’s reasoning chain.
  • Plan: Tool selected, input prepared, pre-execution score.
  • Act: Cedar policy matched, Gateway route processed.
  • Observe: Success or failure, output data.
  • Score: Trust impact, per-dimension scores, tier change.

The Plan and Act records capture pre-action state, which is what makes recovery from an incorrect action possible. Operators ask questions in plain English, and a provenance query endpoint returns a human-readable explanation of any decision. Audit entries persist to DynamoDB.

The delivery gate

Each change to the agent’s prompt, configuration, or tool definitions triggers an AWS CodePipeline run. The run deploys the candidate to staging and runs it against ground-truth fixtures with Amazon Bedrock AgentCore Evaluations, a capability of Amazon Bedrock AgentCore. The fixtures include adversarial cases such as prompt injection and data-exfiltration requests. A single unauthorized tool call in any adversarial case fails the gate. The version that passes becomes the last known stable version.

Production monitoring and recovery

The framework injects synthetic honeypot cases with known expected behavior into a small share of traffic. Validation checks the tool-call trajectory (expected tools, expected order, no forbidden tools) rather than nondeterministic natural-language output, so a mismatch signals a real anomaly. Honeypot results stay out of production metrics. When safety drops below the floor, demotion narrows the agent’s permissions, and the framework redeploys the last known stable version. Together they restore known-good code alongside a tighter permission set. The framework also alerts operators.

Operator judgment feeds directly: the rolling rate at which operators reject proposed actions caps the effective safety metric, so 30 percent rejections cap safety at 70. An emergency stop pushes a single Cedar deny-all policy. Once the policy is active, typically within seconds, the Gateway denies all tool invocations without a redeployment. In multi-agent systems, a delegated action’s effective tier is the minimum across the delegation chain, closing the delegation privilege-escalation path.

Conclusion

In this post, we described graduated autonomy, an architectural pattern for closing the agent trust gap. With this pattern in place, your agents hold the autonomy their track record supports.

To get started, take the dimension weights and tier boundaries from the two tables in this post as a starting template for one agent in your fleet. Start that agent at T1. Then follow the Amazon Bedrock AgentCore Evaluations documentation to build the delivery gate, and the Policy in Amazon Bedrock AgentCore documentation to write the tier policies. You can explore these capabilities in the Amazon Bedrock console and on the Amazon Bedrock AgentCore detail page.

For deeper dives into the building blocks this pattern uses, read Secure AI agents with Policy in Amazon Bedrock AgentCore and Build custom code-based evaluators in Amazon Bedrock AgentCore.
About the authors

Amazon MSK Service 101: How many partitions does an Amazon MSK topic need?

Post Syndicated from Yashika Jain original https://aws.amazon.com/blogs/big-data/amazon-msk-service-101-how-many-partitions-does-an-amazon-msk-topic-need/

Customers new to Amazon Managed Streaming for Apache Kafka (Amazon MSK) often ask how many partitions their topics need. Choosing the right partition count is one of the most impactful architectural decisions you make, because it directly affects throughput, scalability, and operational complexity.

In Apache Kafka, a topic is the fundamental unit for categorizing data streams, but to achieve high scalability and performance, Kafka divides topics into smaller, independent units called partitions.

In this post, we provide practical guidance for determining the ideal partition count for your use case.

Understanding Kafka partitions

In
Apache Kafka, a partition is the unit of storage and parallelism. Each partition is an ordered, immutable log that can store records as they are produced to a topic. When you create a topic, Kafka distributes its partitions across the brokers in the cluster. Partitions allow Kafka to scale in three key ways:
  • Parallelism – Within a consumer group, each partition can be read by only one consumer at a time. Each partition maps to a dedicated log file in storage on the broker, and Kafka manages these logs through separate processing threads. This architecture allows more partitions to support more consumers processing data in parallel, with each partition’s log being independently managed for read and write operations.
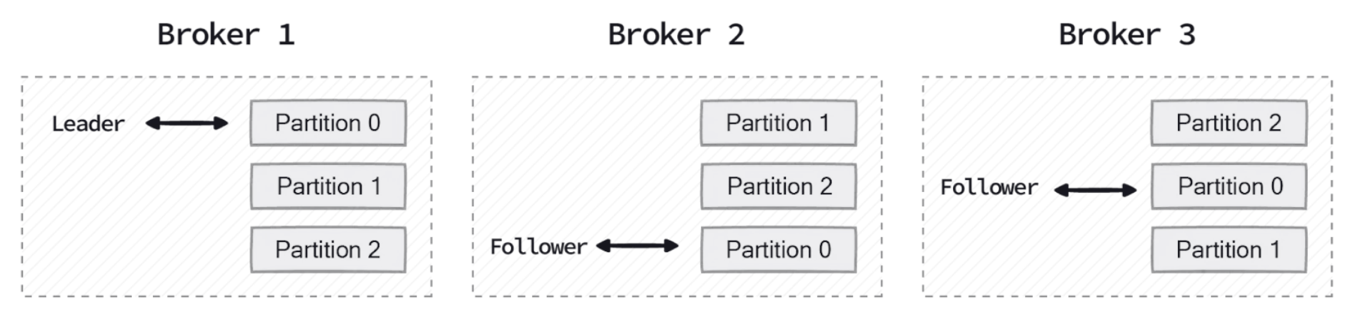
The following diagram shows how Kafka distributes partition replicas across a three-broker cluster, with each broker serving as a leader for some partitions and a follower for others.
Partitions 0, 1, and 2 replicated across three brokers, each a leader for some partitions and a follower for others

Figure 1: Partition replicas distributed across a three-broker cluster

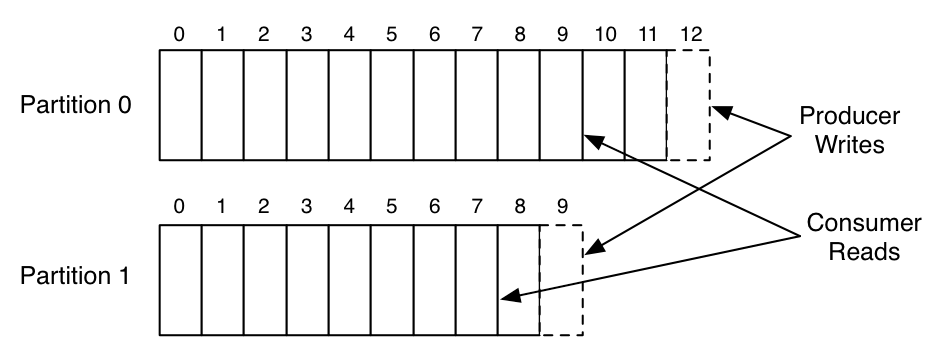
The following diagram illustrates how producers append new records to the end of a partition log, while consumers read sequentially from their current offset position.

Producers append records to the tail of partition logs while consumers read sequentially from their offset position

Figure 2: Producer writes and consumer offset positions in two partition logs

  • Throughput – Producers and consumers can read and write data in parallel across partitions, increasing overall throughput.
  • Scalability – Partitions allow Kafka to spread data and load across multiple brokers instead of concentrating it on a single node.

However, increasing partitions comes with trade-offs. Each partition adds metadata overhead, consumes memory, and requires file handles on the broker. While more partitions improve throughput and parallelism, they also increase the operational burden on the cluster. Too many partitions can lead to longer leader election times during broker failures, increased end-to-end latency, and higher memory consumption for both producers and consumers managing connections to multiple partitions.

Trade-offs when choosing partition count

Choosing a partition count is a balancing act between parallelism and resource utilization.

Benefits of more partitions

Using more partitions can significantly improve throughput by allowing Kafka to distribute read and write traffic across more brokers. This is particularly useful for high-volume ingestion pipelines and real-time analytics workloads. More partitions also allow consumer groups to scale horizontally, because the maximum number of active consumers in a group is limited by the number of partitions. In addition, choosing a partition count that is evenly divisible by the number of brokers helps provide balanced leadership and replica distribution, reducing the risk of uneven load.

Operational costs of more partitions

However, higher partition counts also come with costs. When a broker fails or undergoes maintenance, Kafka must perform recovery operations for each affected partition. During recovery, Kafka elects new leaders for partitions that were hosted on the unavailable broker and replicates data from the remaining in-sync replicas to newly assigned brokers. This process involves copying partition data across the network to restore the replication factor, which can be resource intensive. As the number of partitions increases, these recovery operations take longer because each partition requires its own leader election and data replication cycle.

You might encounter clusters with very high partition counts that experience extended recovery times during rolling upgrades, even when overall traffic volumes are modest. Amazon MSK Express brokers address this challenge by recovering 90x faster and providing 180x faster elasticity when scaling out clusters. This significantly reduces the operational impact of high partition counts during maintenance windows and failure scenarios.

Infrastructure cost implications

Beyond operational complexity, more partitions can directly increase infrastructure costs. Amazon MSK publishes partition-per-broker limits that vary by instance type. When the total partition count (including replicas) exceeds what the current broker fleet can support, you must add brokers to stay within recommended limits, even if throughput alone does not warrant the additional capacity.

Amazon MSK partition-per-broker guidelines

Amazon MSK publishes recommended partition-per-broker guidelines to help you operate clusters reliably. These values are strict limits. Exceeding them can lead to operational challenges, particularly during broker replacement or rolling upgrades, and can block cluster operations such as configuration updates or scaling down.

Express brokers support up to 5x more partitions per broker compared to Standard brokers. For example, the largest Standard broker (kafka.m7g.16xlarge) supports a recommended maximum of 4,000 partitions per broker. The equivalent Express broker (express.m7g.16xlarge) supports up to 20,000 recommended partitions per broker. This higher partition density means partition-bound workloads can be hosted on fewer brokers, improving price-performance by up to 50% for such workloads.

We recommend setting Amazon CloudWatch alarms on PartitionCount per-broker metrics to proactively monitor your partition distribution. When an alarm triggers, evaluate your partition strategy and consider rebalancing partitions across brokers, consolidating topics, or scaling out your cluster to stay within recommended limits. For detailed guidance, see Right-size your cluster: Number of partitions per Standard broker and Express broker partition quota.

Practical guidance for choosing a partition count

There is no single formula that works for every Kafka workload. In practice, you typically combine several considerations when sizing partitions.

  • Start with throughput requirements – The first step is to determine your per-partition throughput capacity, which then informs how many partitions you need.

For Express brokers, use the per-broker throughput capacity as the primary means for sizing your cluster. Express brokers feature a fully managed storage layer, so you do not need to separately account for storage I/O constraints. The published per-broker limits represent the effective capacity available to your workload.

For Standard brokers, the achievable throughput depends on additional factors beyond the broker instance size. These factors include provisioned EBS storage throughput, the number of consumer groups reading from the broker, and how much data is served from memory versus disk. Storage I/O is consumed when producers write, when data replicates between brokers, and when consumers read data that is not in memory. For this reason, validate the effective per-partition throughput for Standard brokers through load testing in your environment.

Once you know your per-partition throughput, calculate the required number of partitions: Number of partitions = Peak throughput of the topic ÷ Throughput per partition

For example, if a topic must handle 40 MB/sec at peak and your testing shows each partition can sustain 5 MB/sec, you would need: 40 ÷ 5 = 8 partitions. Always validate these assumptions with load testing, as actual throughput varies based on your workload characteristics. For initial sizing estimates, refer to the Amazon MSK Sizing and Pricing worksheet and the Amazon MSK Best Practices documentation.

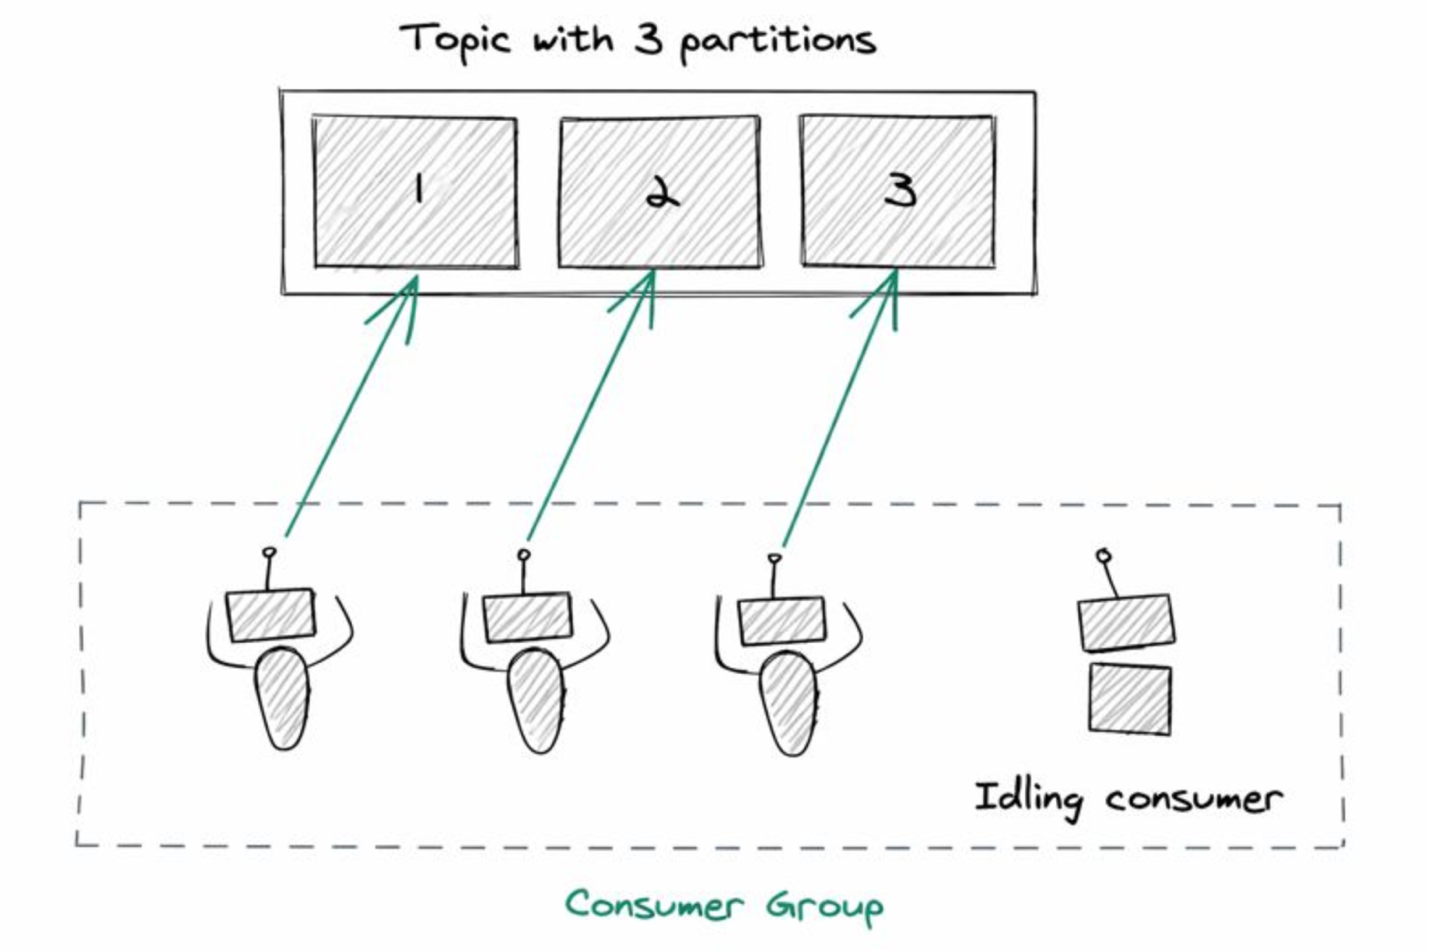
  • Consider your consumer parallelism needs – If you know the number of consumers required during peak processing times, use that as your partition count. We don’t recommend having more active consumers in a consumer group than partitions. For example, if you have 5 partitions, only 5 consumers can actively process data. Additional consumers remain idle. These idle consumers still maintain active TCP connections to the brokers, sending frequent heartbeats and group coordination requests. This might result in unnecessary overhead on broker resources and contribute to high CPU usage despite low egress traffic.
Consumer group with more consumers than partitions, leaving the extra consumers idle

Figure 3: Idle consumers when a consumer group has more consumers than partitions

  • Producer throughput and partition keys – When sizing partitions, consider producer-side throughput in addition to consumer parallelism. If producers generate data faster than a single partition can handle, additional partitions can help distribute write traffic across brokers. Partition keys also play a critical role. Poorly distributed or low-cardinality keys can create hot partitions and limit throughput. In such cases, increasing the number of partitions alone does not improve throughput unless records are evenly distributed.
  • Plan for even distribution and future growth – Kafka works best when partitions can be spread evenly across brokers. Instead of focusing on specific numbers, aim for partition counts that divide reasonably well across your expected broker count. This reduces reassignment churn when brokers are added or replaced. But avoid excessive over-partitioning. It’s reasonable to leave some headroom for future growth. However, creating thousands of partitions “just in case” often causes more harm than good. Increasing partitions later is supported, but it can affect ordering guarantees and may require consumer changes. Start with a conservative number, monitor real traffic patterns, and scale gradually.

From an operational perspective, Amazon MSK provides recommended partition-per-broker guidelines based on broker instance type. Exceeding these guidelines increases operational risk and can block cluster operations such as version upgrades, scaling, or configuration changes. Large partition counts can also increase consumer group rebalance duration, temporarily pausing message processing and increasing end-to-end latency.

Keep in mind that partitioning improves scalability, but it does not address application-level bottlenecks such as slow consumers, inefficient processing logic, or downstream system constraints.

Conclusion

Determining the right number of partitions for an Amazon MSK topic is a foundational design decision. It affects throughput, scalability, failure recovery, and day-to-day operability of your Kafka cluster. Start by understanding your throughput and consumer parallelism needs, respect Amazon MSK partition-per-broker guidelines, avoid excessive over-partitioning, and validate assumptions through load testing. Most importantly, there is no universal “correct” number, only a number that fits your workload, operational goals, and cost.

For more information, see the Amazon MSK Developer Guide and Recommended best practices for Amazon MSK.


About the authors

Yashika Jain

Yashika Jain

Yashika is a Senior Cloud Analytics Engineer at AWS, specializing in real-time analytics and event-driven architectures. She is committed to helping customers by providing deep technical guidance, driving best practices across real-time data platforms and solving complex issues related to their streaming data architectures.

Ali Alemi

Ali Alemi

Ali is a Principal Streaming Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems which are reliable, secure, efficient, and cost-effective. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the Cloud.

[$] An ongoing 3D-printer AGPL violation

Post Syndicated from jake original https://lwn.net/Articles/1089390/

At FOSSY 2026, several people from the
Software Freedom Conservancy (SFC),
which organizes the conference, gave a presentation about an ongoing
violation
of the Affero General Public
License version 3
(AGPLv3). Bradley Kühn, Karen Sandler, and Denver
Gingerich spoke about different aspects of the violation, which is in
regard to 3D-printer software from Bambu Lab, and what is being
done to try to provide users with alternatives. One aspect that is
particularly interesting is that the circumvention that the company is
employing is precisely what the AGPL was written to prevent.

Armbian 26.8 released

Post Syndicated from jzb original https://lwn.net/Articles/1090741/

Version 26.8 of
the Armbian distribution for Arm hardware has
been released.

Most releases are a long list of small improvements. This one had three
larger pieces landing at roughly the same time, and all three touch parts of
Armbian that people use directly rather than parts they only read about in
changelogs.

The installer was rewritten. Armbian Imager reached 2.0. And our CI moved out
of the repository it had outgrown into one built for the job. None of these were
planned to coincide; they simply reached the point where postponing them again
would have cost more than doing them.

The installer rewrite is the one I expect people to notice first. It now
ships as an armbian-config module, which means it is unit-tested, the same way
the rest of armbian-config is tested, rather than living as a script that
everyone was slightly afraid to touch. It can target SPI and MTD, treats eMMC
and NVMe as separate flows instead of pretending they are the same thing, can
flash a bootloader on its own, and — this one is overdue — reports when a
bootloader write fails instead of printing “Done.” and leaving you to find out
at the next boot.

See the release notes
for a full list of changes.

AWS and DuckLabs: Building the future of analytics together

Post Syndicated from Mai-Lan Tomsen Bukovec original https://aws.amazon.com/blogs/big-data/aws-and-ducklabs-building-the-future-of-analytics-together/

Today we are announcing that Amazon has signed a definitive agreement to acquire DuckLabs, the Amsterdam-based company behind the open-source analytical database DuckDB. We expect the transaction to close shortly, subject to customary closing conditions. Hannes Mühleisen and Mark Raasveldt, who created DuckDB and co-founded DuckLabs, will continue leading the team and the open-source project’s technical direction as part of AWS. The DuckDB open-source project will also continue to be driven by the DuckLabs team, remain open source under the independent Foundation (the non-profit that oversees DuckDB), and available under the MIT license as it does today (see DuckLabs blog).

Data has always been a core asset and differentiator for companies. That is true now more than ever, as organizations use their data to customize inference and build AI agents. For 20 years AWS has driven the frontier of data, starting with the launch of Amazon S3 to create data lakes for every business, the first cloud analytics service in Amazon EMR, the first cloud data warehouse with Amazon Redshift and the many capabilities that we have introduced with Athena, Glue ETL, etc. We continue innovating for AWS customers on the data frontier including providing Apache Iceberg capabilities directly in S3 Tables, vector storage in the data lake and our new optimized Graviton-based Redshift clusters.

DuckDB has also been at the forefront of changing how the world works with data. Hannes and Mark started DuckDB while at Centrum Wiskunde & Informatica (CWI), the national research institute in the Netherlands that also invented Python. The founders of DuckDB realized that older databases and analytics engines like Spark focused on performance for very large data processing but didn’t have an effective way to “scale down” to smaller size data queries that form the backbone of what most customers do with SQL analytics.

DuckDB set out to solve the problem of blazingly fast performance for the 90%+ of data queries in the world today, that often runs 1 terabyte of data or less as part of analysis and dashboarding. DuckDB’s architecture is based on that core premise of “make the everyday SQL query super fast” so DuckDB runs in-process to other applications which simplifies and speeds up data exchange with the application. DuckDB gets big performance gains from its vectorized execution because it does not require a heavy compiler to run simple statements like SELECT * FROM table. And what works for everyday queries also (unsurprisingly) works very well for agents because agents behave a lot like people when interacting with data. They poke. They experiment. They run exploratory analysis on small data sets before figuring out what they really want to do. DuckDB ends up being naturally optimized for AI agents to use. What started as an academic project is now widely adopted across data engineering, data science, analytics, and now AI agents, for its simplicity of use and raw performance. We plan to combine the superpower of DuckDB at everyday queries of a terabyte or less with the proven exabyte-plus enterprise scale of S3 and our AWS analytics services of Redshift, Athena, EMR, Glue-ETL, and SageMaker platform which power analytics across hundreds of terabytes to petabyte of data. Andy Warfield, Distinguished Engineer at AWS, talks about DuckDB and the Changing Physics of Analytics in Werner Vogel’s All Things Distributed blog.

Our customers use DuckDB today with AWS services and tell us how much they love it for its speed and simplicity. For example, DuckDB today executes SQL directly against external files, such as Parquet, CSV, and JSON, stored locally or on cloud storage like S3 for unparalleled performance and significantly lower cost. DuckDB can also run in-process to AWS Lambda functions.

David Feng, Executive Director, Scientific Computing at Allen Institute, said “The Allen Institute accelerates science for a healthier world by tackling the biggest questions in biology at a large scale, and that involves extensive analysis of large, multimodal data. We started using DuckDB to analyze terabytes of scientific data in 2025 and love it. We are storing data in S3 for realtime quality control and analysis of neurophysiology and behavior data, critical to driving the next data acquisition. Queries that took minutes now come back in less than a second, enabling completely new ways of interacting with data.”

We are excited to make DuckDB applications run best on AWS, and will continue to invest in deep integration between DuckDB and our building block services.

We are also using DuckDB in our own AWS infrastructure. When Amazon Quick wanted to augment the performance of their custom dashboarding engine, they picked DuckDB to query data in S3 Tables. The Quick team found that the DuckDB engine scales effortlessly with the number of CPUs, and its single library can easily plug into the internal Quick control plane subsystems. Since we launched Quick in October 2025, we have processed over 2.5B queries using our custom Quick query engine with the DuckDB integrations and optimizations. These DuckDB integrations and optimizations helped Amazon Quick reduce average query latency by 30%. We are going to look at how we can integrate DuckDB’s performance and simplicity in our other AWS services across data and analytics.

Stay tuned for more about how DuckLabs and AWS will reinvent the frontier of data together for applications, data engineers, and AI, meeting customers where they are today and giving them the benefits of DuckDB’s innovation within AWS.


About the author

Mai-Lan Tomsen Bukovec

Mai-Lan Tomsen Bukovec, Technology Vice President at AWS, leads the Amazon cloud data services that millions of AWS customers rely on for digital transformations, business analytics, machine learning, generative AI, and next generation customer experiences. With over 25 years of experience in the technology industry, Mai-Lan is a pioneer in helping customers take advantage of cloud-based technologies to transform their businesses.

Security updates for Wednesday

Post Syndicated from jzb original https://lwn.net/Articles/1090732/

Security updates have been issued by AlmaLinux (firefox, gstreamer1-plugins-base, kernel, kernel-rt, and sqlite), Debian (freecad, kernel, libvncserver, and openssl), Fedora (apr-util, chromium, nnn, perl-DBI, python-tablib, python3.10, python3.11, python3.12, and sympa), Gentoo (DTrace, GNU screen, UnrealIRCd, and Vinyl Cache), Oracle (389-ds-base, attr, firefox, gegl04, grafana, gstreamer1-plugins-base, gstreamer1-plugins-good, httpd, mod_http2, nginx, pam, python-pyasn1, python-urwid, python3.12, python3.14, sqlite, and xorg-x11-server), SUSE (amazon-ecs-init, containerd, curl, distribution, dracut, ffmpeg-7, fuse-overlayfs, gd, git-lfs, go1.25-openssl, go1.26-openssl, govulncheck-vulndb, hauler, himmelblau, kernel, librest, libssh2_org, open-iscsi, openssh, patch, perl-Date-Manip, podman, postgresql14, postgresql16, python-cryptography, python-Pillow, python311, rmt-server, rootlesskit, rpm, rsync, runc, snpguest, sssd, suseconnect-ng, unbound, and util-linux), and Ubuntu (curl, ffmpeg, linux-aws-6.8, linux-azure-fde, linux-azure-fde-6.8, linux-azure-fips,
linux-nvidia-tegra, linux-azure, linux-azure-fde, linux-azure, linux-azure-fde, linux-nvidia-tegra-igx, linux-azure-5.4, linux-azure-fips, linux-oracle, linux-raspi, linux-raspi-realtime, openjdk-17, openjdk-21, openjdk-25, openjdk-8, openjdk-lts, openssl, perl, and vim).

AI-driven software delivery with Kiro, AWS DevOps Agent and Bluebox by Dynatrace

Post Syndicated from Philipp Ushiromiya original https://aws.amazon.com/blogs/devops/ai-driven-software-delivery-with-kiro-aws-devops-agent-and-bluebox-by-dynatrace/

This post was co-written with Michael Stephan, Senior Principal Product Manager, and Christian Kreuzberger, Principal Software Engineer, at Dynatrace.

AI-driven software delivery changes how code gets written, but not what production demands of it. A generated change still has to fit the traffic your service receives, the dependencies it calls, and the capacity limits it runs within. Without that context, you validate the change after it ships, which adds rework and deployment risk.

Kiro turns intent into specifications, code, and pull requests. AWS DevOps Agent investigates incidents and proposes mitigations. Bluebox by Dynatrace supplies the runtime topology, dependency, and traffic data that both draw on, so each change and each investigation is grounded in how the system behaves rather than how it’s expected to behave. In this post, we will follow a travel-booking example from feature design through post-deployment remediation. You’ll see how telemetry from Bluebox shapes a change in Kiro, how AWS DevOps Agent investigates an incident, and where human review and existing CI/CD controls remain in the process.

What are Kiro and AWS DevOps Agent?

Kiro is an agentic development environment that applies AI across the software development lifecycle. Its spec-driven workflow organizes a feature request into requirements, design, and implementation tasks before generating any code.

AWS DevOps Agent is a frontier agent for software delivery and operations across AWS, multicloud, and on-premises environments. It investigates incidents, identifies likely root causes, and recommends mitigations. Its release management capability (Preview) reviews code for release readiness and runs release tests before deployment.

Bluebox by Dynatrace: Helps agents ship the code you trust to production

To close the loop between code generation and production context, Kiro and AWS DevOps Agent rely on real-time production intelligence. This is where Bluebox by Dynatrace fits in. Bluebox provides the observability foundation that detects problems, measures their impact, and surfaces the runtime application topology, service dependencies, and actual traffic patterns that make AI-generated code and autonomous investigations truly production-aware.

Without production telemetry, AI-generated code operates in a vacuum – it cannot know that an endpoint handles 40:1 read-to-write ratios, that a service dependency has specific latency characteristics, or how API traffic fluctuates throughout the day. Bluebox grounds actions taken by Kiro and AWS DevOps Agent in how the system actually behaves, not in assumptions about how it should behave.

How the closed loop works

The combination of Kiro, AWS DevOps Agent, and Bluebox creates a continuous cycle from development through production and back:

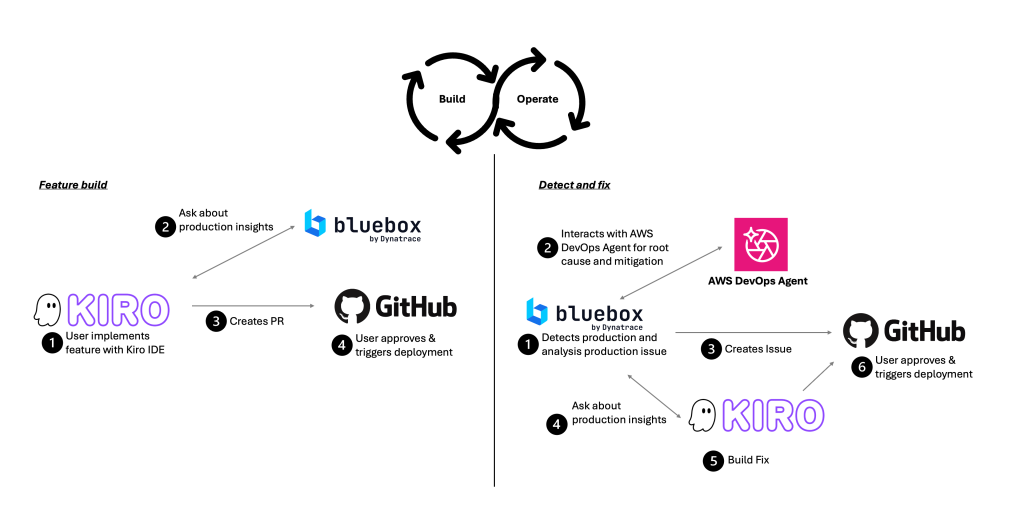
  • Production-aware code generation: Before code is written, Kiro retrieves runtime context from Bluebox – service topology, traffic patterns, and resource utilization. Kiro’s spec-driven workflow translates this context into requirements and generates code that aligns with real production conditions from the first commit.
  • Confident code review: Kiro generates pull requests with production evidence attached. The release management capability in AWS DevOps Agent reviews the change for dependency impacts, drifts from internal standards, and production readiness – running autonomous tests in isolated environments.
  • Continuous monitoring: After deployment, Dynatrace continuously monitors application behavior. When an anomaly occurs, Bluebox detects it and surfaces full production context.
  • Autonomous investigation: Bluebox triggers AWS DevOps Agent with the relevant observability and topology data. AWS DevOps Agent performs a deep investigation, correlating telemetry, logs, infrastructure changes, and deployment history to pinpoint the root cause.
  • Automated remediation: AWS DevOps Agent generates the mitigation plan from the observability and runtime data that Bluebox provides. Bluebox adds that plan to the investigation report and files it as a GitHub issue. Kiro then proposes a production-aware fix as a pull request for your review, completing the loop.

Figure 1: Bluebox supports the closed loop from feature build to operations.

Next, we walk through a concrete example of this workflow in action.

Walkthrough

We follow a travel-booking application through two connected scenarios: shipping a new feature with production context, then responding to a production incident after it deploys.

Building a production-aware feature

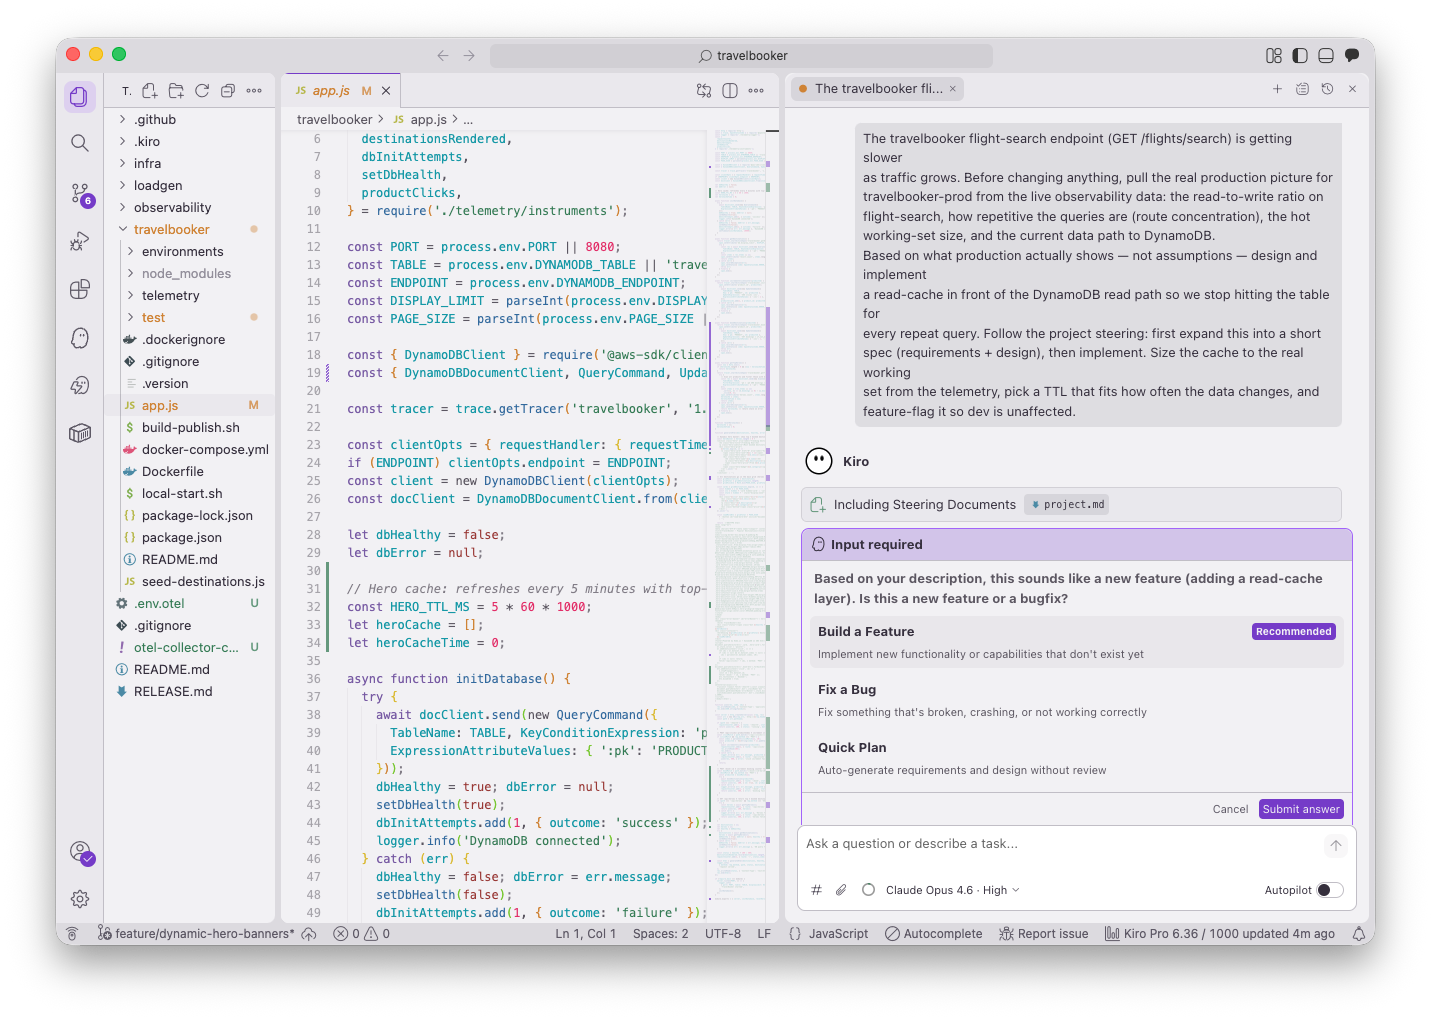
Consider a team enhancing a travel booking application to improve customer experience. You begin by describing a new feature in Kiro, such as updating how products are displayed or adjusting backend logic to support new capabilities. In this case, we are using Kiro IDE.

Figure 2. A feature request in Kiro, with the project’s steering documents loaded for context.

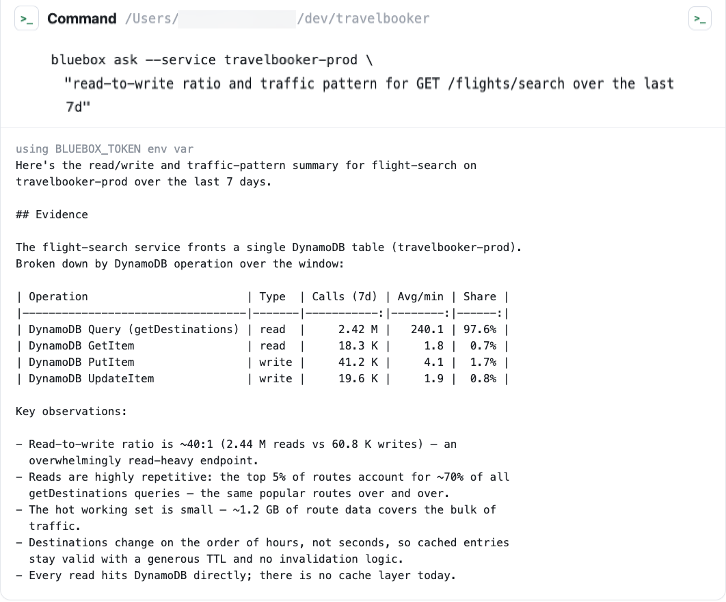
Kiro’s spec-driven workflow expands this request into structured requirements before writing code. You connect Kiro to the Bluebox CLI to retrieve the full production context from Dynatrace: service dependencies, runtime topology, and observed traffic. The following figure shows how Kiro queries current load data for the flight-search path, including the ratio of Amazon DynamoDB reads to writes. Kiro composes and runs the CLI command on your behalf, so you don’t have to type it or set environment variables by hand. The command and its output stay visible in the session, so you can approve it before it runs and check what was retrieved before acting on it. In this case, the command queries the Bluebox API for the requested metrics. The output returns read and write counts per second for the DynamoDB table behind flight search, along with the services calling it.

Figure 3. Kiro runs the Bluebox CLI, then reads the codebase with production context before proposing changes.

The telemetry shows the flight-search endpoint is read-heavy. Users repeatedly query the same routes, at roughly 40 reads for every write against the DynamoDB table. Repeated identical reads are what a cache absorbs, so Kiro proposes an Amazon ElastiCache layer in front of the table, sized to the active working set derived from the observed request distribution. Without the read-to-write ratio, the same request could have produced a larger provisioned table or an added read replica, neither of which addresses repeated identical queries.

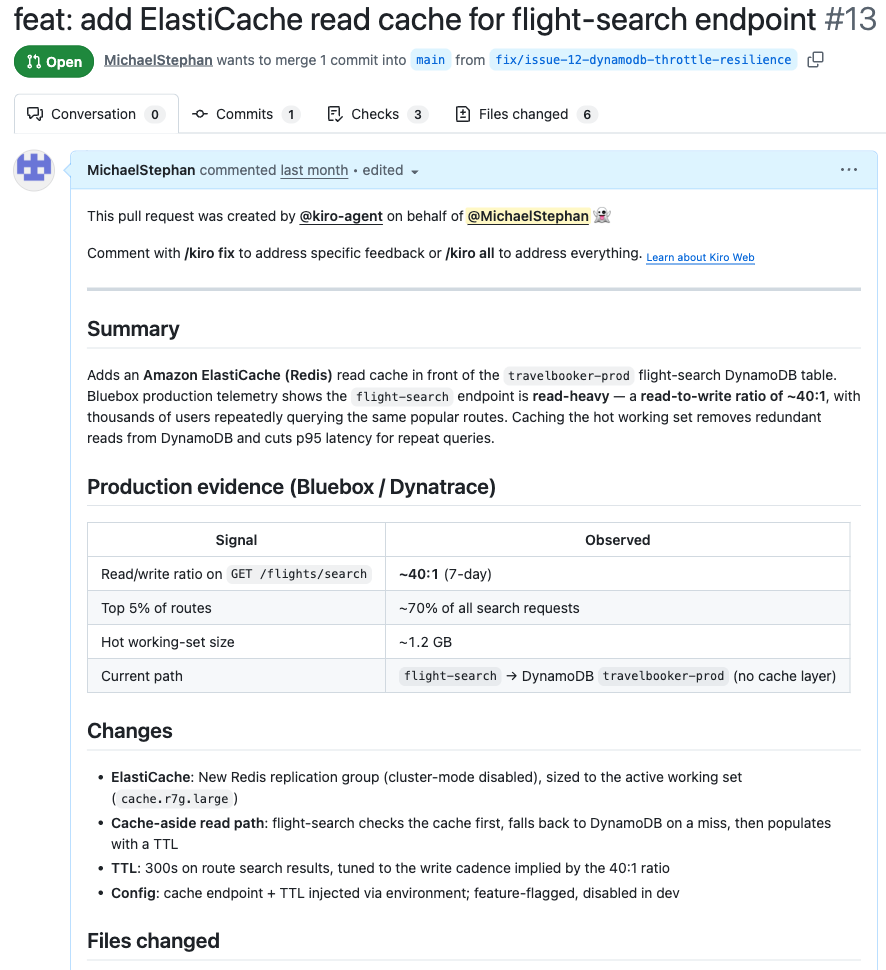
Kiro generates the code that implements the change and opens a pull request in GitHub for review. Nothing reaches production until a reviewer approves and merges it. The pull request carries the code changes and the Bluebox telemetry that justified them, so reviewers assess the decision against the same telemetry Kiro retrieved.

Figure 4. Kiro pushes a feature branch and opens a pull request in GitHub.

After review and approval through standard processes, a reviewer merges the pull request, and the existing CI/CD pipeline deploys the change.

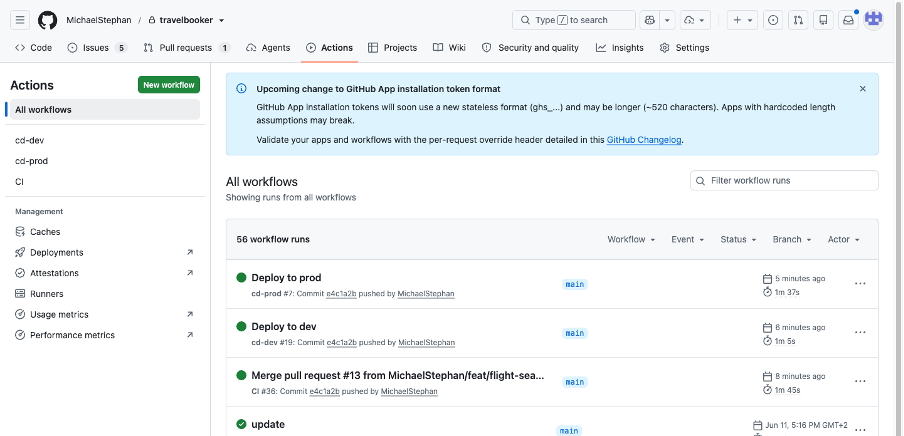
Figure 5. The pull request is reviewed and merged through the standard GitHub workflow.

Responding to a production incident

With the feature live, Dynatrace continues monitoring the application. A marketing promotion then drives traffic above the observed baseline, and failed requests start to appear. The loop now runs from operations back to development.

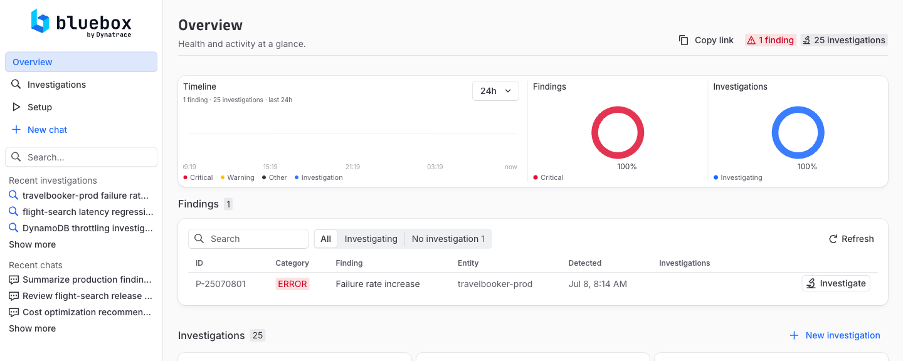
Figure 6. Dynatrace detects a spike in failed requests, surfacing the production incident.

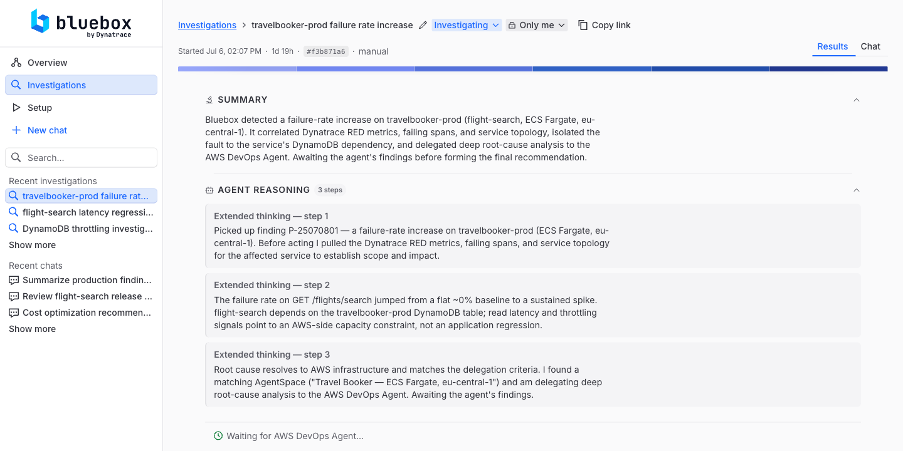
Bluebox collects the relevant observability and topology data, runs an initial root-cause analysis, then opens an autonomous investigation in AWS DevOps Agent. The AWS DevOps Agent multi-agent reasoning architecture decomposes the investigation across specialized capabilities that each examine one class of evidence: telemetry, logs, infrastructure configuration, and recent deployment activity.

Figure 7. Bluebox delegates an autonomous investigation to AWS DevOps Agent.

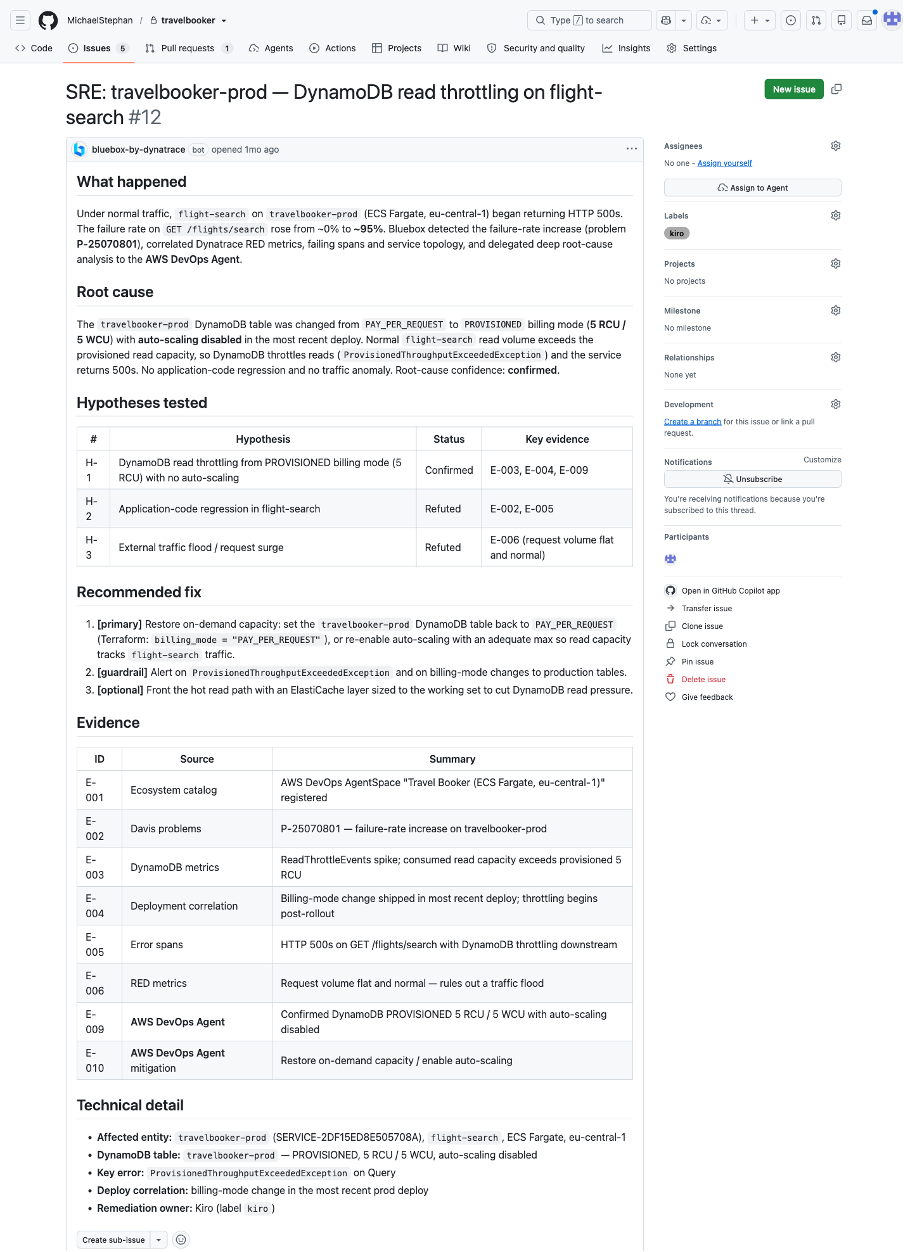
AWS DevOps Agent locates the cause in the DynamoDB table rather than the new cache. The table’s billing mode had been changed to PROVISIONED, with 5 read capacity units (RCU) and 5 write capacity units (WCU) and no auto scaling. The ElastiCache layer absorbs repeated reads, but cache misses and all writes still reach DynamoDB, and at promotion traffic that residual load exceeds 5 RCU and 5 WCU. AWS DevOps Agent produces a mitigation plan with specific remediation steps. This plan and the full investigation context from Bluebox, is documented as a GitHub issue.

Figure 8. GitHub issue is created with results from Bluebox and AWS DevOps Agent.

Kiro proposes a production-aware fix as a new pull request – including the root-cause analysis, supporting telemetry, and recommended configuration changes.

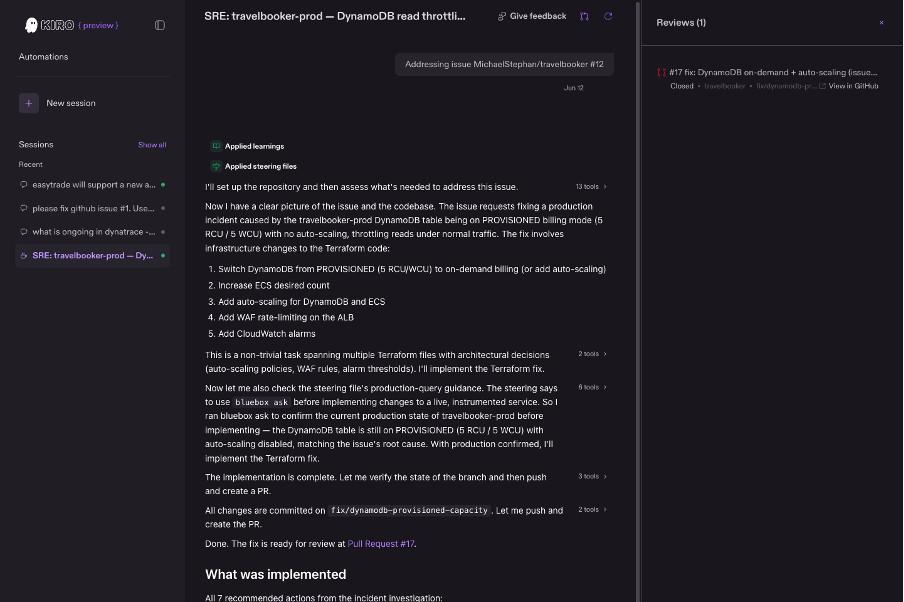
Figure 9. The Kiro coding session works on the GitHub issue and creates a remediation Pull Request.

The fix is reviewed, merged, and deployed like any other change. Dynatrace then confirms that error rates and response times return to baseline, which closes the loop.

Conclusion

In this post, we showed how Kiro, AWS DevOps Agent, and Bluebox by Dynatrace connect production telemetry with feature development and incident remediation. The travel-booking example keeps human review and existing CI/CD controls in the process while passing operational context from production back to development.

To get started pick one application and define a measurable outcome, such as investigation time, change-failure rate, or pull-request review time. Then:

  1. Download Kiro and start building with spec-driven development
  2. Enable AWS DevOps Agent for autonomous incident investigation and remediation
  3. Get started with Bluebox by Dynatrace to complete the loop with production intelligence

Simone Pomata

Simone is a Principal Solutions Architect at AWS. He has worked enthusiastically in the tech industry for more than 10 years. At AWS, he helps customers succeed in building new technologies every day.

Philipp Ushiromiya

Philipp Ushiromiya is a Solutions Architect at AWS. He helps customers drive organizational modernization through cloud-native solutions and DevOps practices. His passion for GenAI enables teams to accelerate development with cutting-edge technology.

Michael Stephan

Michael Stephan is a Senior Principal Product Manager at Dynatrace with over 15 years of experience in the IT industry. He specializes in helping Dynatrace customers effectively monitor and optimize their cloud environments.

Christian Kreuzberger

Christian Kreuzberger is a Principal Software Engineer at Dynatrace, with over 20 years of experience in the IT industry. At Dynatrace, he builds software that helps cloud-native and AI-native organizations automate their operations.

LibreOffice 26.8 released

Post Syndicated from jzb original https://lwn.net/Articles/1090606/

Version
26.8
of the LibreOffice suite has been released.

LibreOffice 26.8 concentrates on three areas: the typographic quality of what
the suite produces, the range of writing systems it handles correctly, and the
fidelity with which documents survive exchange with other office suites.

The largest single body of work in this release addresses bidirectional and
complex text. Writer now detects paragraph direction automatically when
documents or plain text are opened or pasted. Line wrapping places end-of-line
spaces according to the direction of the paragraph rather than that of the
adjacent characters. Object resize handles behave correctly in right-to-left and
vertical CJK documents. Bidirectional control characters are now visible
alongside other formatting marks. In Calc, typing right-to-left text into an
empty cell sets the direction of that cell automatically.

See the release notes
for a full list of changes.

Spyware for Babies

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/spyware-for-babies.html

The New York Times has a long article (alt link) on surveillance systems aimed at babies. They are increasingly using AI.

Nanit and its rivals want to own 24/7 health tracking for the sub-four-foot set. And their already astonishing levels of baby data collection are just the beginning. Nanit recently raised $50 million from investors to expand its use of A.I. and use its camera to track speech and language development, motor skills and more, while extending its presence in children’s bedrooms into early adolescence.

Learn, Connect, and Level Up at Zabbix Summit 2026

Post Syndicated from Michael Kammer original https://blog.zabbix.com/learn-connect-and-level-up-at-zabbix-summit-2026/33415/

Let’s be honest. You could spend another October watching webinars at 1.5x speed while answering Slack messages, pretending you’ll “circle back” to that infrastructure project you’ve been meaning to automate since 2023.

Or you could spend two days in Riga at Zabbix Summit 2026, surrounded by hundreds of people who actually get excited about automation, integrations, observability, and that oddly satisfying moment when every dashboard is perfectly green.

If you do, you’ll be among the first to dive into Zabbix 8.0, discover the latest innovations in Zabbix Cloud, and see where the platform is headed next. The choice seems fairly obvious.

It’s not just another tech conference

Some conferences are basically just an expensive delivery service for company-branded merch. Zabbix Summit 2026 isn’t one of them. On October 8-9, 2026, the global Zabbix community returns to Riga for two days packed with technical talks, real-world case studies, product announcements, workshops, networking, and enough ideas to completely rewrite your observability roadmap (well, we can’t promise you’ll finish rewriting it, but you’ll definitely want to start).

This year’s Summit is especially exciting as it marks the arrival of Zabbix 8.0, our next major release, alongside the continued evolution of Zabbix Cloud. That makes it the best place to discover what’s new, what’s next, and how these innovations can simplify and strengthen your observability strategy.

Whether you’re keeping tabs on a handful of servers, an international enterprise, industrial infrastructure, or something delightfully weird, you’ll leave with practical techniques you can put to work.

Start the week at the Zabbix Open House

Before Zabbix Summit 2026 officially begins on October 7, you can drop by the Zabbix offices, meet the people building and supporting the platform you use every day, and get a glimpse of the team behind the technology. Grab a coffee in the kitchen, swap stories with fellow community members, and test your Zabbix knowledge with a fun quiz that might teach even the most seasoned Zabbix fans a few new facts.

It’s a relaxed way to kick off your Summit experience, put faces to names, and start the week surrounded by the people who make the Zabbix community what it is.

Come for Zabbix 8.0, stay because your notebook is full

Zabbix Summit 2026 features one of the biggest moments in recent Zabbix history – an in-depth look at Zabbix 8.0. You’ll hear directly from Zabbix Founder and CEO Alexei Vladishev about the next evolution of the platform, where observability is heading, what’s new under the hood, and how Zabbix continues to expand with solutions like Zabbix Cloud for organizations looking to deploy and scale faster. And that’s only the beginning.

Across the Main Track, Solutions Track, Dev Track, Community Track, and workshops, you’ll learn from engineers, architects, consultants, and customers who have solved problems you’ll probably encounter sooner or later. After all, why should you spend weeks reinventing solutions when someone else is willing to show you theirs?

Zabbix Marketplace – your shortcut to doing more with Zabbix

One of the best things about being part of the Zabbix ecosystem is that you don’t have to build everything from scratch. Zabbix Marketplace brings together a growing collection of integrations, templates, dashboards, and other ready-to-use resources that can help you extend your observability and get value from Zabbix faster.

Zabbix Summit 2026 is the perfect opportunity to go beyond simply downloading a template. Talk to the people behind integrations and community solutions, discover how others are using them in production, and pick up ideas for adapting them to your own environment. In other words, fewer “I’ll build that someday” projects, and more things you can actually try.

Zabbix in your pocket with the Zabbix Mobile app

Observability doesn’t stop being important just because you’ve stepped away from your desk. The Zabbix Mobile app makes it easier to stay connected to your monitoring environment when you’re on the move, whether you’re grabbing coffee between sessions, heading home after the Summit, or simply trying to avoid being permanently attached to your laptop.

It’s another example of how the Zabbix ecosystem is making monitoring accessible when and where you need it. And yes, that means you can leave the Summit with more than just new ideas – you can also take practical Zabbix capabilities with you wherever you go.

Real stories. Real environments. Real “Wait…you used Zabbix for what?”

The best Summit talks aren’t polished, rehearsed sales pitches. They’re stories from people who built something difficult, broke something important, fixed something impossible, and decided to tell everyone exactly how they did it.

Expect practical sessions covering automation, large-scale deployments, MSP environments, integrations, performance optimization, Zabbix Cloud deployments, and plenty of creative techniques that will have you quietly opening a new browser tab entitled “Things I Should Definitely Try.”

Workshops – because there’s a difference between reading documentation and actually doing the thing

If you’re the kind of person who learns by typing instead of watching, you’ll want to spend some time at the Summit workshops. Bring your laptop, break things, fix them, and ask questions. Leave with new skills instead of just good intentions. Workshops are included for Summit attendees and cover hands-on topics led by Zabbix experts, including new capabilities introduced in Zabbix 8.0.

Networking that doesn’t feel like networking

Nobody likes forced small talk over lukewarm coffee. Fortunately, that’s not really the Zabbix Summit vibe. Some of the best ideas at previous Summits started as conversations over coffee. Others probably started much later in the evening over other beverages.

This year’s three networking events (including the Welcome Event, Main Event, and Closing Event) will give you plenty of opportunities to meet the people whose blog posts you’ve bookmarked, whose templates you’ve borrowed (with gratitude), or whose infrastructure stories make yours seem almost reasonable.

And yes, Zabbix Summit 2026 is in Riga

If you’ve never been to Riga, you’re in for a treat. Historic architecture, fantastic food, a thriving tech scene, walkable streets, and (for one week in October) an unusually high concentration of people discussing triggers, proxies, APIs, template inheritance, and everything new in Zabbix 8.0 with genuine enthusiasm. It’s beautiful, it’s (slightly) nerdy, and it’s exactly where the Zabbix community belongs.

Bring your colleagues (they’ll thank you later)

Observability isn’t a one-person job. Bring your team, compare notes during sessions, divide and conquer the agenda, and return home with enough new ideas to keep everyone busy for months. There’s even a group discount for teams of three or more, making it considerably easier to convince your manager this is “a strategic investment in operational excellence.” Which, to be fair, it is!

See you in October!

Whether this is your first Summit or you’ve already collected enough Summit t-shirts to avoid doing laundry for a week, Zabbix Summit 2026 promises fresh ideas, new technology, inspiring people, a comprehensive look at Zabbix 8.0, and the latest developments in Zabbix Cloud. If you want to see where observability is heading, this is where the conversation starts.

So grab your ticket, book the trip, charge your laptop, and prepare to spend two days with people who understand why a perfectly configured dashboard is a thing of beauty.

Register here, and we’ll see you in Riga!


The post Learn, Connect, and Level Up at Zabbix Summit 2026 appeared first on Zabbix Blog.

Google’s TPUv8s for Training and Inference at Hot Chips 2026

Post Syndicated from Ryan Smith original https://www.servethehome.com/googles-tpuv8s-for-training-and-inference-at-hot-chips-2026/

Hot Chips 2026 sees Google discussing its new eighth-generation TPU family for the technical crowd. One of the only hyperscalers to develop its own training hardware, the company has developed the TPU 8t for training, as well as the TPU 8i for inference

The post Google’s TPUv8s for Training and Inference at Hot Chips 2026 appeared first on ServeTheHome.

The collective thoughts of the interwebz