Secondary school maths showing that AI systems don’t think

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/secondary-school-maths-showing-that-ai-systems-dont-think/

At a time when many young people are using AI for personal and learning purposes, schools are trying to figure out what to teach about AI and how (find out more in this summer 2025 data about young people’s usage of AI in the UK). One aspect of this is how technical we should get in explaining how AI works, particularly if we want to debunk naive views of the capabilities of the technology, such as that AI tools ‘think’. In this month’s research seminar, we found out how AI contexts can be added to current classroom maths to make maths more interesting and relevant while teaching the core concepts of AI.
Prof. Dr. Martin Frank, Assistant Prof. Dr. Sarah Schönbrodt, Research Associate Stephan Kindler

At our computing education research seminar in July, a group of researchers from the CAMMP (Computational and Mathematical Modeling Program) research project shared their work:

  • Prof. Dr. Martin Frank, Founder of CAMMP (Karlsruhe Institute of Technology (KIT), Germany).
  • Assistant Prof. Dr. Sarah Schönbrodt (University of Salzburg, Austria)
  • Research Associate Stephan Kindler (Karlsruhe Institute of Technology (KIT), Germany)

They talked about how maths already taught in secondary schools can be used to demystify AI. At first glance, this seems difficult to do, as it is often assumed that school-aged learners will not be able to understand how these systems work. This is especially the case for artificial neural networks, which are usually seen as a black box technology — they may be relatively easy to use, but it’s not as easy to understand how they work. Despite this, the Austrian and German team have developed a clear way to explain some of the fundamental elements of AI using school-based maths.

Sarah Schönbrodt started by challenging us to consider that learning maths is an essential part in developing AI skills, as: 

  1. AI systems using machine learning are data-driven and are based on mathematics, especially statistics and data
  2. Authentic machine learning techniques can be used to bring to life existing classroom maths concepts
  3. Real and relevant problems and associated data are available for teachers to use

A set of workshops for secondary maths classrooms

Sarah explained how the CAMMP team have developed a range of teaching and learning materials on AI (and beyond) with an overall goal to “allow students to solve authentic, real and relevant problems using mathematical modeling and computers”. 

She reflected that much of school maths is set in contexts that are abstract, and may not be very interesting or relevant to students. Therefore, introducing AI-based contexts, which are having a huge impact on society and students’ lives, is both an opportunity to make maths more engaging and also a way to demystify AI.
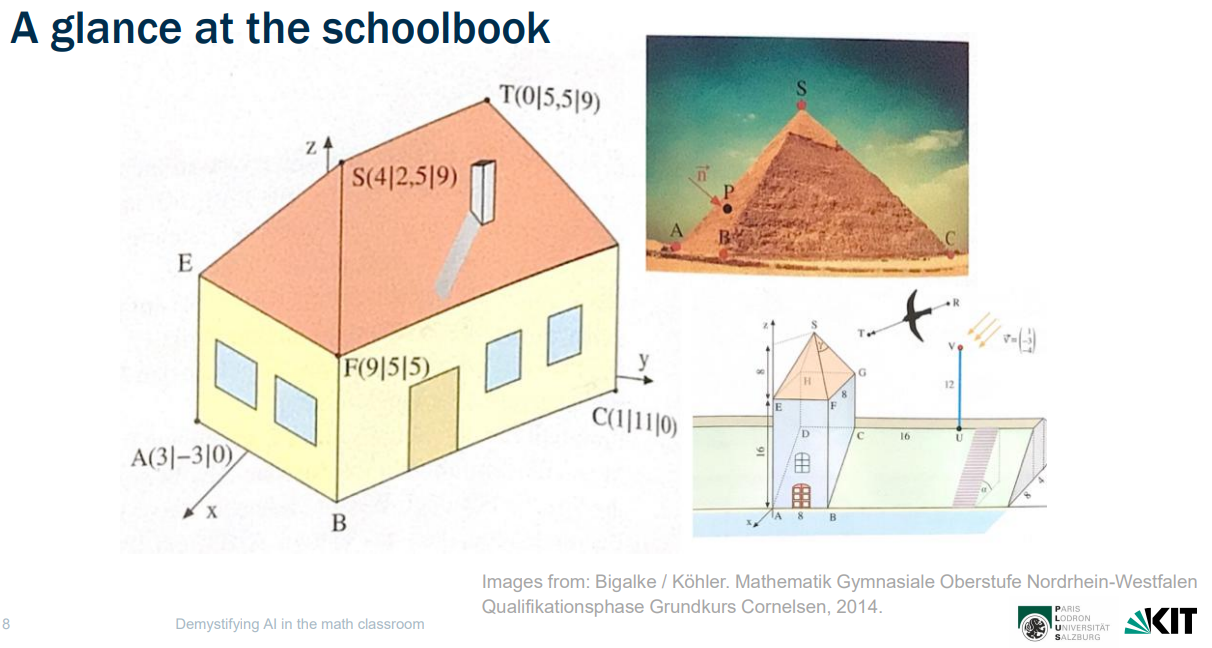
A glance at the schoolbook diagram
Old-fashioned contexts are often used to teach classroom maths concepts. Those same concepts could be taught using real-world AI contexts. (Slide from the researchers’ presentation.)

Workshops designed and researched by the team include contexts such as privacy in social networks to learn about decision trees, personalised Netflix recommendations to learn about k-nearest neighbour, word predictions to learn about N-Grams, and predicting life expectancy to learn about regression and neural networks.

Learning about classification models: traffic lights and the support vector machine

For the seminar, Sarah walked through the steps to learn about support vector machines. This is an upper secondary workshop for students aged 17 to 18 years old. The context of the lesson is an image problem — specifically, classifying the data representing the colours of a simplified traffic light system (two lights to start with) to work out if a traffic light is red or green.

She walked through each of the steps of the maths workshop:

  • Plotting data points of two classes, the representation of green and red traffic lights
  • Finding a line that best separates the data points of both classes
  • Figuring out what best is
  • Classifying the data points in relation to the chosen (separating) line
  • Validating the model statistically to see if it is useful in classifying new data points, including using test data and creating a contingency table (also called a confusion matrix)
  • Discussing limitations, including social and ethical issues
  • Explaining how three traffic lights can be expressed as three-dimensional data by using planes
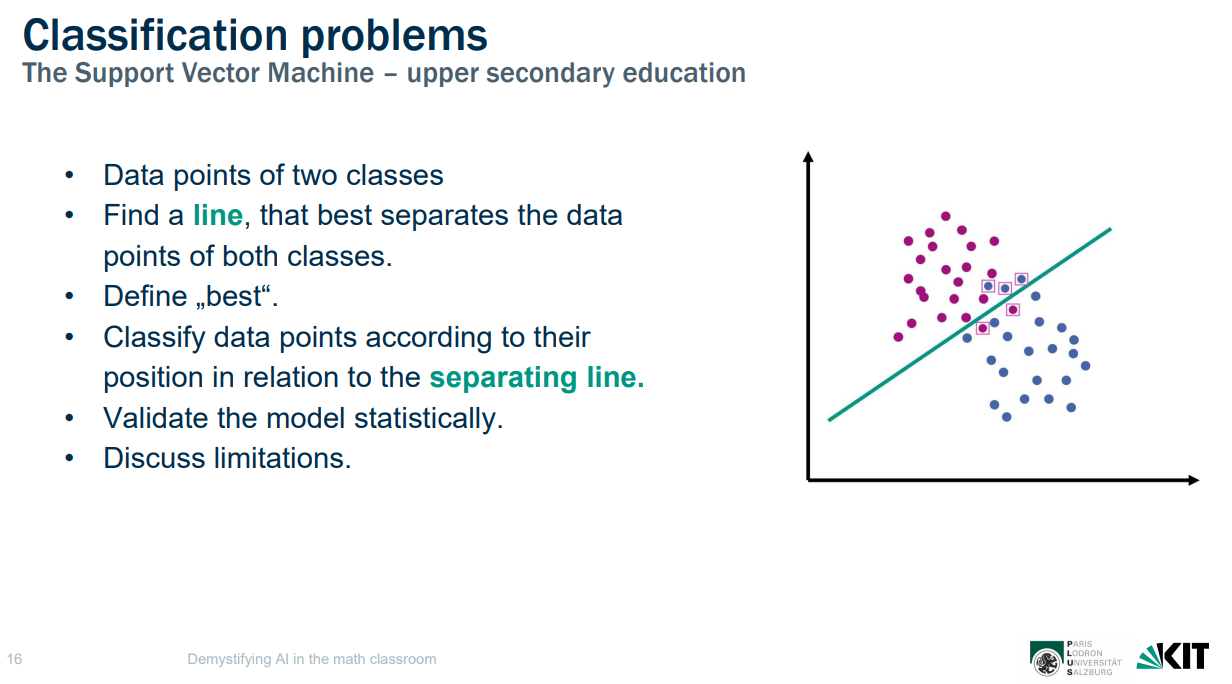
Classification problems diagram
By classifying green and red traffic light data, students are learning about lines, classifying data, and considering limitations. (Slide from the researchers’ presentation.)

Throughout the presentation, Sarah pointed out where the maths taught was linked to the Austrian and German mathematics curriculum.
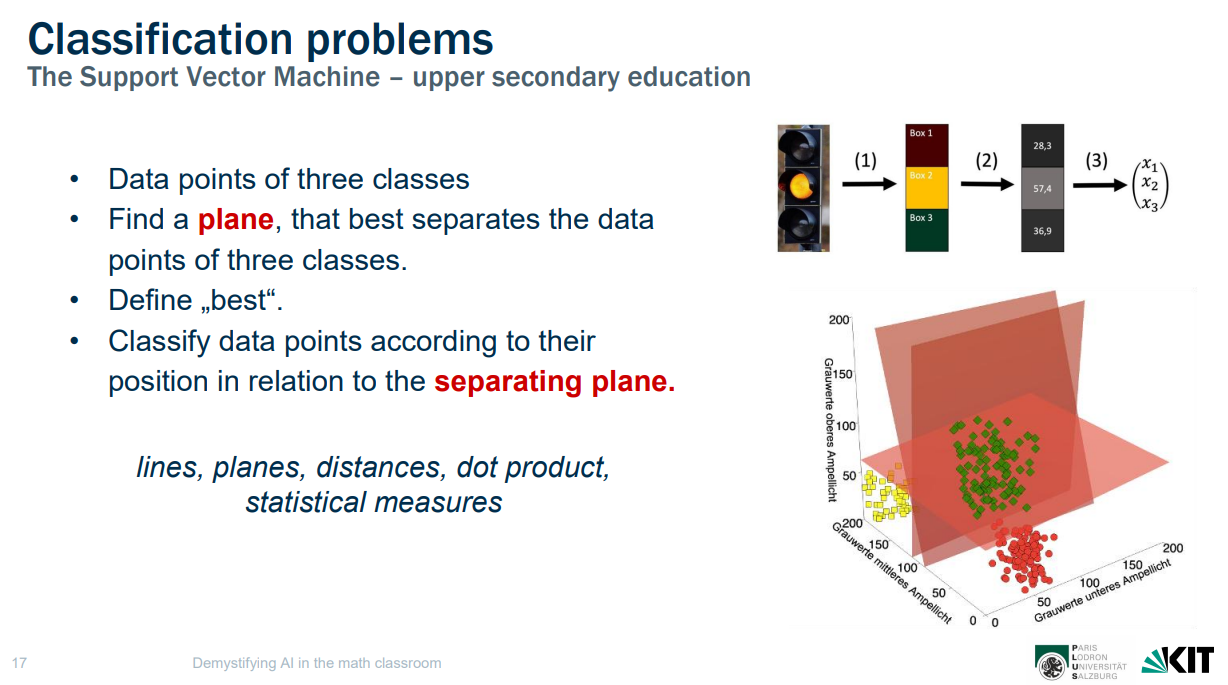
Classification problems diagram
Learning about planes, separating planes, and starting to see how data can be represented in vectors. (Slide from the researchers’ presentation.)

Learning about social and ethical issues
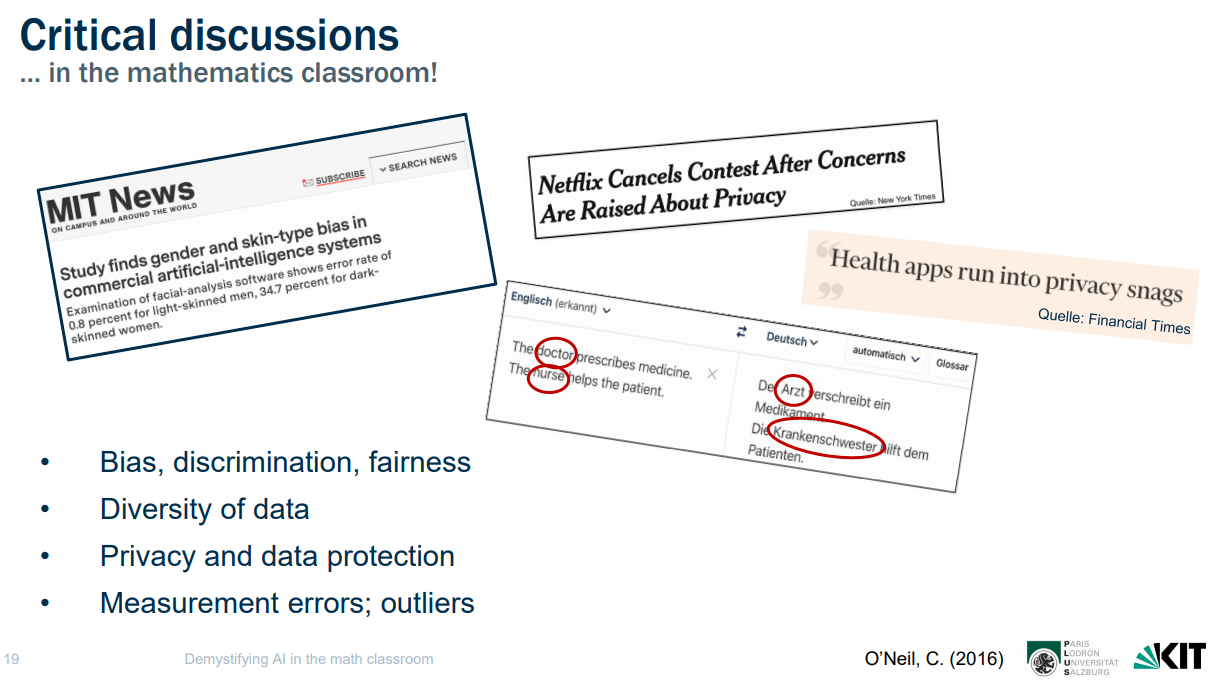
Learning about the social and ethical issues in data-driven systems. (Slide from the researchers’ presentation.)

As well as learning about lines, planes, distances, dot product and statistical measures, learners are also engaged in discussing the social and ethical issues of the approach taken. They are encouraged to think about bias, data diversity, privacy, and the impact of errors on people. For example, if the model wrongly predicts a light as green when it is red, then an autonomous car would run through a red traffic light. This would likely be a bigger consequence than stopping at a green traffic light that was mis-predicted as red. So should the best line reduce this kind of error?

To teach the workshops, Sarah explained they have developed interactive Jupyter notebooks, where no programming skills are needed. Students fill in the gaps of example code, explore simulations, and write their ideas for discussion for the whole class. No software needs to be installed, feedback is direct, and there are in-depth tasks and staggered hints.

Learning about regression models: Weather forecasting and the toy artificial neural network

Stephan went on to introduce artificial neural networks (ANNs), which are the basis of generative AI applications like chatbots and image generation systems. He focused on regression models, such as those used in weather forecasting. 

ANNs are very complex. Therefore, to start to understand the fundamentals of this technology, he introduced a ‘toy ANN’ with one input, three nodes, and one output. A function is performed on the input data at each node. With the toy network, the team wants to tackle a major and common misconception: that students think that ANN systems learn, recognise, see, and understand, when really it’s all just maths.
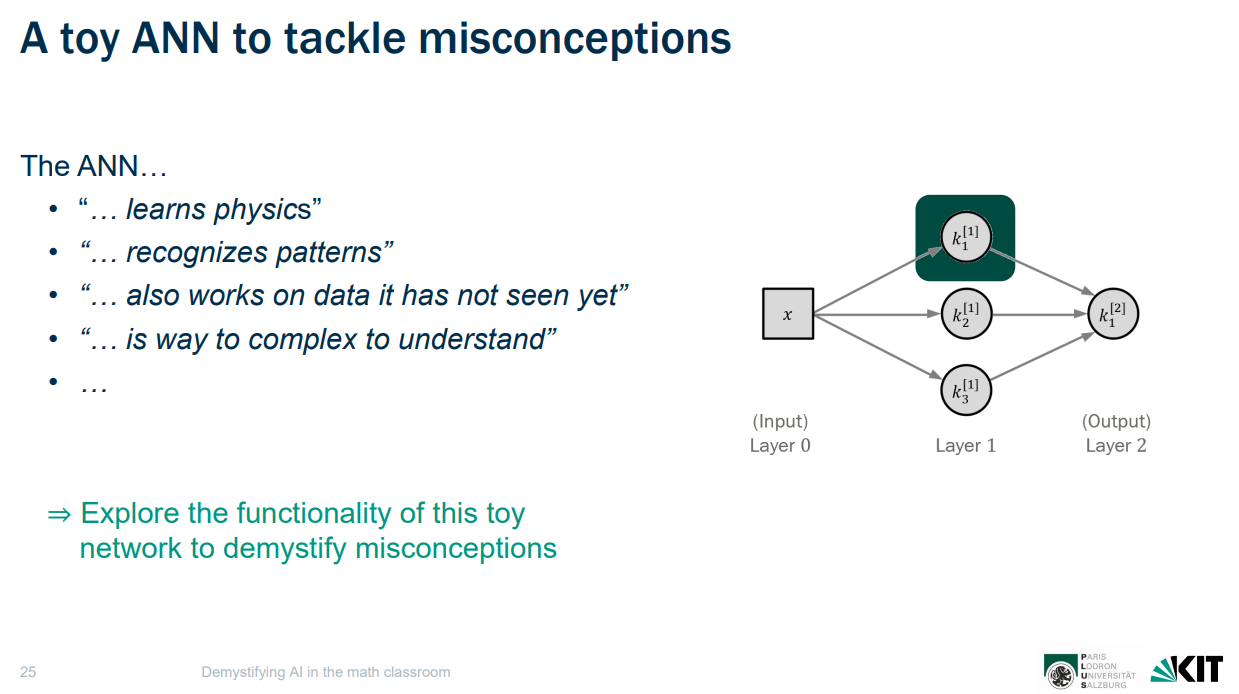
Tackling misconceptions about ANNs by exploring how they work in a toy version. (Slide from the researchers’ presentation.)

The learning activity starts by looking at one node with one input and one output, and can be described as a mathematical function, with a concatenation of two functions (in this case a linear and activation function). Stephan shared an online simulator that visualises how the toy neural network can be explored as students change two parameters (in this case, weight and bias of the functions). Students then look at the overall network, and the way that the output from the three nodes is combined. Again, they can explore this in the simulator. Students compare simple data about weather prediction to the model, and discover they need more functions — more nodes to better fit the data. The activity helps students learn that ANN systems are just highly adjustable mathematical functions that, by adding nodes, can approximate relationships in a given data set. But the approximation only works in the bounds (intervals) in which data points are given, showing that ANNs do not ‘understand’ or ’know’ — it’s just maths.

Stephen finished by explaining the mutual benefits of AI education and maths education. He suggested maths will enable a deeper understanding of AI, and give students a way to realistically assess the opportunities and risks of AI tools and show them the role that humans have in designing AI systems. He also explained that classroom maths education can benefit from incorporating AI contexts. This approach highlights how maths underpins the design and understanding of everyday systems, supports more effective teaching, and promotes an interdisciplinary way of learning across subjects.

Some personal reflections — which may not be quite right!

I have been researching the teaching of AI and machine learning for around five years now, since before ChatGPT and other similar tools burst on the scene. Since then, I have seen an increasing number of resources to teach about the social and ethical issues of the topic, and there are a bewildering number of learning activities and tools for students to train simple models. There are frameworks for the data lifecycle, and an emerging set of activities to follow to prepare data, compare model types, and deploy simple applications. However, I felt the need to understand and to teach about, at a very simple level, the basic building blocks of data-driven technologies. When I heard the CAMMP team present their work at the AIDEA conference in February 2025, I was entirely amazed and I asked them to present here at our research seminar series. This was a piece of the puzzle that I had been searching for — a way to explain the ‘bottom of the technical stack of fundamental concepts’. The team is taking very complex ideas and reducing them to such an extent that we can use secondary classroom maths to show that AI is not magic and AI systems do not think. It’s just maths. The maths is still hard, and teachers will still need the skills to carefully guide students step by step so they can build a useful mental model. 

Photo of a class of students at computers, in a computer science classroom.

I think we can simplify these ideas further, and create unplugged activities, simulations, and ways for students to explore these basic building blocks of data representation, as well as classification and representing approximations of complex patterns and prediction. I can sense the beginnings of new ideas in computational thinking, though they’re still taking shape. We’re researching these further and will keep you updated.

Finding out more

If you would like to find out more about the CAMMP resources, you can watch the seminar recording, look at the CAMMP website or try out their online materials. For example, the team shared a link to the jupyter notebooks they use to teach the workshops they demonstrated (and others). You can use these with a username of ‘cammp_YOURPSEUDONYM’, where you can set ‘YOURPSEUDONYM’ to any letters, and you can choose any password. They also shared their toy ANN simulation.
The CAMMP team are not the only researchers who are investigating how to teach about AI in maths lessons. You can find a set of other research papers here.

Join our next seminar

In our current seminar series, we’re exploring teaching about AI and data science. Join us at our last seminar of the series on Tuesday, 27 January 2026 from 17:00 to 18:30 GMT to hear Salomey Afua Addo talk about using unplugged approaches to teach about neural networks.

To sign up and take part, click the button below. We’ll then send you information about joining. We hope to see you there.

The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars page.

The post Secondary school maths showing that AI systems don’t think appeared first on Raspberry Pi Foundation.

Security updates for Friday

Post Syndicated from jzb original https://lwn.net/Articles/1050251/

Security updates have been issued by AlmaLinux (firefox, luksmeta, mysql, mysql:8.0, mysql:8.4, tomcat, and wireshark), Debian (chromium, kernel, and tzdata), Fedora (brotli, dr_libs, perl-Alien-Brotli, python-urllib3, singularity-ce, wireshark, and yarnpkg), Oracle (firefox, grafana, lasso, libsoup3, luksmeta, ruby, ruby:3.3, tomcat, and wireshark), Slackware (mozilla), SUSE (container-suseconnect, kubernetes-client, libpoppler-cpp2, postgresql14, postgresql15, and python3), and Ubuntu (c-ares, keystone, linux, linux-aws, linux-aws-5.15, linux-azure, linux-gcp, linux-gcp-5.15,
linux-gke, linux-gkeop, linux-hwe-5.15, linux-ibm, linux-ibm-5.15,
linux-intel-iotg, linux-intel-iotg-5.15, linux-lowlatency,
linux-lowlatency-hwe-5.15, linux-nvidia, linux-nvidia-tegra,
linux-nvidia-tegra-5.15, linux-nvidia-tegra-igx, linux-oracle,
linux-oracle-5.15, linux-xilinx-zynqmp, linux-azure, linux-azure-4.15, linux-oracle,, linux-fips, linux-aws-fips, linux-azure-fips, linux-gcp-fips, linux-fips, linux-aws-fips, linux-gcp-fips, linux-hwe-6.8, linux-oracle-6.8, linux-raspi, linux-realtime, linux-intel-iot-realtime, and python-urllib3).

Идва ли освобождение след оставката?

Post Syndicated from Емилия Милчева original https://www.toest.bg/idva-li-osvobozhdenie-sled-ostavkata/

Идва ли освобождение след оставката?

В действителност протестиращите по площадите и улиците на България и Европа десетки хиляди български граждани не искаха оставката на правителството. Те искат освобождение от модела „Борисов – Пеевски“ и от мрежите му. Падането на правителството на Росен Желязков е само първият пробив в стената. 

Същинският оздравителен процес ще започне с изваждането от политиката на лидера на ГЕРБ Бойко Борисов и на санкционирания за корупция от САЩ и Великобритания олигарх Делян Пеевски. А тази работа може да свърши прокуратурата, ако пожелае да служи на държавността и да изпълнява функциите си на защитник на обществения интерес вместо на куче пазач на завладяната от „Борисов–Пеевски“ държавност. 

Формулата на бившата правосъдна министърка на Румъния Моника Маковей „Изчистете съдебната система и тя ще изчисти всичко останало“ не проработи в България.

Сега държавното обвинение е заключено в отколешните си зависимости – мудно и удобно за силните на деня. Но от него зависи ще има ли освобождение след оставката, или всичко ще остане само в периметъра на протестния шум. 

Също и от гражданската енергия – ще нарасне ли още до предсрочните парламентарни избори (вероятно през март), или ще спадне и как ще се трансформира в избирателна активност. Замлъкне ли улицата, избутаните в ъгъла на ринга бързо ще се окопитят и оставката ще е само моментен триумф.

„Все пак е победа, да се порадваме за малко“, казва таксиметровият шофьор, който със съжаление отбелязва, че не е успял за третия, най-многоброен протест, тъй като му се паднал дълъг курс извън София. Точно след този протест и преди гласуването на шестия вот на недоверие правителството подаде оставка, а премиерът Росен Желязков я мотивира с „гласа на народа“:

Ние, както заявихме нееднократно, чуваме гласа на гражданите, които протестират срещу управлението. Чуваме го осъзнато. Затова и трябва да бъдем на висотата на техните искания. Техните искания са за оставка на правителството. Това е настоящият момент. За оставката глас издигнаха и млади, и стари, хора от различни етноси, от различни религии.

51-вото Народно събрание няма да успее да произведе второ правителство, след като основните политически сили декларираха отказ да участват в преговори за нов кабинет. Както е тръгнало, няма да участват и в гласуването на редактирания проектобюджет за 2026 г., което означава, че поне до юни догодина държавата ще остане със старата финансова рамка, тоест с удължителен бюджет. Няма нови програми или увеличения на разходи (освен ако не се гласува отделно за извънредни ситуации), следователно в МВР, МО, ДАТО и навсякъде, където възнагражденията са увеличени, ще се запазят сегашните нива на заплащане.

Ако слушаме Борисов, ГЕРБ излиза от това 11-месечно управление с вдигната глава и след „брилянтни действия“. Също така нямало защо да се сърдят на „децата на площада“ – той като тийнейджър мечтаел семейният москвич да стане лада:

Защо им се сърдим, че искат да мечтаят? Да имат мечти. Я се замислете вие като сте били на тия години, за какво сте си мечтали. Аз дори съм благодарен, че Господ не ме е чул. Мечтата ми беше москвичът на татко да стане лада. Това ми беше и само си виках: „Ей, Господи, само това ми дай. Нищо друго няма да поискам. Една лада да карам аз.“ Това ми беше мечтата на тия години, 15–16–17. Те затова и площадът им е празник.

Изглежда, че Борисов е изключение от максимата „Човек е толкова голям, колкото големи са мечтите му“. Въпреки скромните дори и за социалистически младеж мечти, той създаде и оглави най-голямата партия в най-новата история на България, три пъти беше премиер, а футболният отбор „Витоша (Бистрица)“, в който играе, спечели тази година и купата при ветераните. 

За какво мечтае Борисов днес, е въпрос за 1 милион евро. В последния си трети мандат той караше гигантска тойота, през чийто отворен прозорец „разхвърляше“ пари като на селска сватба, все едно няма правила, програми, проекти за публичните средства.

„Зурлички“ навсякъде

Положението сега е „Борисов–Пеевски“ падна! Да живее „Борисов–Пеевски!“. Причината да се перифразират изрази от протокола на френския кралски двор е, че от всеки регулатор и институция надничат „зурлички“ – наложените от „Борисов–Пеевски“ и избрани от мнозинството кандидати. Те могат да бламират и провалят всяка смислена инициатива, а засега неуспешно „се справят“ с овладяване на ръста на цените.

За дългия път към промяната предупреди и съпредседателят на „Демократична България“ Ивайло Мирчев:

Кабинета го свалиха хората, които излязоха масово на площадите няколко пъти поред. […] Тази нова гражданска енергия, това връщане на гражданското общество всъщност беше правилният път. Но това е само първа стъпка към свалянето на кабинета. Но това е първа стъпка към разграждането на този модел.

Какво ще се случи с гражданската енергия до предсрочните избори (евентуално) през март, е в пряка връзка с действията след 1 януари. Повишението на цените има потенциал да разгневи гражданите и от протест за ценностите на демокрацията да преминат към социален. Тази промяна би предопределила и политическите сили, които ще се възползват от страховете на обществото и от неговия гняв.

Системата, която създава и укрепва на власт персони като Борисов и Пеевски, не е счупена – така че битката за нормална европейска България предстои. Поредната.

Политиците ще трябва да се равняват по гражданското недоволство. А на площадите хората идваха гневни поради различни причини, но с общ знаменател – несправедливост в разпределението на публичните средства, несправедливост в правораздаването, несправедливост в достъпа до услуги и възможности, които би трябвало да са универсални за всички. Държавата работи за малка група привилегировани и наказва останалите с бюрократичен произвол, несигурност и непрозрачност.

Предсрочните избори също така ще са тест за президентските наесен. Ще запази ли ГЕРБ преднина? Дали коалицията ПП–ДБ ще капитализира гражданската енергия и ще се утвърди като реален политически фактор преди президентския вот? Къде ще са Пеевски и неговото ДПС – Ново начало? Социологическо проучване на „Маркет Линкс“ им отрежда четвърто място с резултат 9,1%. В същото време ГЕРБ губи значителен дял от подкрепата си само за три месеца. Спадът от 22 на 17% е заради протестите, бюджет 2026 и кризата във властта.

Радев ще скочи ли?

За предстоящите парламентарни избори на Румен Радев ще му се наложи да напусне президентските покои и да скочи в бурния водовъртеж на политиката. Така предизборната кампания на вицето му Илияна Йотова ще започне с поемането на президентския пост. 

Ако иска избиратели, доскорошният държавен глава ще трябва да изостави патетичните обръщения към нацията и да стане интерактивен играч на политическата сцена. Президентът, който през последните години се позиционира като глас на гражданската енергия, има възможност да даде сигнал за продължаване на натиска върху модела „Борисов–Пеевски“. 

Досегашните му действия обаче показват предпазливост – изказванията са ясни, но реалните стъпки за подпомагане на реформаторските процеси са не просто оскъдни, а липсват. Въпреки това и ГЕРБ, и ПП–ДБ са уклончиви относно бъдещи съвместни действия с президентски проект. В този вакуум на доверие и разочарование Румен Радев стои на старта на изборната надпревара, за да се опита да се утвърди като ключов фактор в следващата политическа конфигурация. 

За българските демократи е добре да помнят, че всъщност е преоблечен Орбан.

Building Trustworthy AI Agents

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/12/building-trustworthy-ai-agents.html

The promise of personal AI assistants rests on a dangerous assumption: that we can trust systems we haven’t made trustworthy. We can’t. And today’s versions are failing us in predictable ways: pushing us to do things against our own best interests, gaslighting us with doubt about things we are or that we know, and being unable to distinguish between who we are and who we have been. They struggle with incomplete, inaccurate, and partial context: with no standard way to move toward accuracy, no mechanism to correct sources of error, and no accountability when wrong information leads to bad decisions.

These aren’t edge cases. They’re the result of building AI systems without basic integrity controls. We’re in the third leg of data security—the old CIA triad. We’re good at availability and working on confidentiality, but we’ve never properly solved integrity. Now AI personalization has exposed the gap by accelerating the harms.

The scope of the problem is large. A good AI assistant will need to be trained on everything we do and will need access to our most intimate personal interactions. This means an intimacy greater than your relationship with your email provider, your social media account, your cloud storage, or your phone. It requires an AI system that is both discreet and trustworthy when provided with that data. The system needs to be accurate and complete, but it also needs to be able to keep data private: to selectively disclose pieces of it when required, and to keep it secret otherwise. No current AI system is even close to meeting this.

To further development along these lines, I and others have proposed separating users’ personal data stores from the AI systems that will use them. It makes sense; the engineering expertise that designs and develops AI systems is completely orthogonal to the security expertise that ensures the confidentiality and integrity of data. And by separating them, advances in security can proceed independently from advances in AI.

What would this sort of personal data store look like? Confidentiality without integrity gives you access to wrong data. Availability without integrity gives you reliable access to corrupted data. Integrity enables the other two to be meaningful. Here are six requirements. They emerge from treating integrity as the organizing principle of security to make AI trustworthy.

First, it would be broadly accessible as a data repository. We each want this data to include personal data about ourselves, as well as transaction data from our interactions. It would include data we create when interacting with others—emails, texts, social media posts—and revealed preference data as inferred by other systems. Some of it would be raw data, and some of it would be processed data: revealed preferences, conclusions inferred by other systems, maybe even raw weights in a personal LLM.

Second, it would be broadly accessible as a source of data. This data would need to be made accessible to different LLM systems. This can’t be tied to a single AI model. Our AI future will include many different models—some of them chosen by us for particular tasks, and some thrust upon us by others. We would want the ability for any of those models to use our data.

Third, it would need to be able to prove the accuracy of data. Imagine one of these systems being used to negotiate a bank loan, or participate in a first-round job interview with an AI recruiter. In these instances, the other party will want both relevant data and some sort of proof that the data are complete and accurate.

Fourth, it would be under the user’s fine-grained control and audit. This is a deeply detailed personal dossier, and the user would need to have the final say in who could access it, what portions they could access, and under what circumstances. Users would need to be able to grant and revoke this access quickly and easily, and be able to go back in time and see who has accessed it.

Fifth, it would be secure. The attacks against this system are numerous. There are the obvious read attacks, where an adversary attempts to learn a person’s data. And there are also write attacks, where adversaries add to or change a user’s data. Defending against both is critical; this all implies a complex and robust authentication system.

Sixth, and finally, it must be easy to use. If we’re envisioning digital personal assistants for everybody, it can’t require specialized security training to use properly.

I’m not the first to suggest something like this. Researchers have proposed a “Human Context Protocol” (https://papers.ssrn.com/sol3/ papers.cfm?abstract_id=5403981) that would serve as a neutral interface for personal data of this type. And in my capacity at a company called Inrupt, Inc., I have been working on an extension of Tim Berners-Lee’s Solid protocol for distributed data ownership.

The engineering expertise to build AI systems is orthogonal to the security expertise needed to protect personal data. AI companies optimize for model performance, but data security requires cryptographic verification, access control, and auditable systems. Separating the two makes sense; you can’t ignore one or the other.

Fortunately, decoupling personal data stores from AI systems means security can advance independently from performance (https:// ieeexplore.ieee.org/document/ 10352412). When you own and control your data store with high integrity, AI can’t easily manipulate you because you see what data it’s using and can correct it. It can’t easily gaslight you because you control the authoritative record of your context. And you determine which historical data are relevant or obsolete. Making this all work is a challenge, but it’s the only way we can have trustworthy AI assistants.

This essay was originally published in IEEE Security & Privacy.

Т.Е. от Е.Т. – епизод 35

Post Syndicated from Тоест original https://www.toest.bg/t-e-ot-e-t-epizod-35/

Т.Е. от Е.Т. – епизод 35

Оставката е подадена от т.нар. министър-председател. Сега остава и да има за кого да гласуваме – и животът ще дойде по-хубав от песен.
Какво още? Е.Т. обобщава.


Следете видеорубриката на Елена Телбис за „Тоест“ и във Facebook, Instagram и TikTok.

Exploring the new AWS European Sovereign Cloud: Sovereign Reference Framework

Post Syndicated from Andreas Terwellen original https://aws.amazon.com/blogs/security/exploring-the-new-aws-european-sovereign-cloud-sovereign-reference-framework/

At Amazon Web Services, we’re committed to deeply understanding the evolving needs of both our customers and regulators, and rapidly adapting and innovating to meet them. The upcoming AWS European Sovereign Cloud will be a new independent cloud for Europe, designed to give public sector organizations and customers in highly regulated industries further choice to meet their unique sovereignty requirements. The AWS European Sovereign Cloud expands on the same strong foundation of security, privacy, and compliance controls that apply to other AWS Regions around the globe with additional governance, technical, and operational measures to address stringent European customer and regulatory expectations. Sovereignty is the defining feature of the AWS European Sovereign Cloud and we’re using an independently validated framework to meet our customers’ requirements for sovereignty, while delivering the scalability and functionality you expect from the AWS Cloud.

Today, we’re pleased to share further details about the AWS European Sovereign Cloud: Sovereign Reference Framework (ESC-SRF). This reference framework aligns sovereignty criteria across multiple domains such as governance independence, operational control, data residency and technical isolation. Working backwards from our customers’ sovereign use cases, we aligned controls to each of the criteria and the AWS European Sovereign Cloud is undergoing an independent third-party audit to verify the design and operations of these controls conform to AWS sovereignty commitments. Customers and partners can also leverage the ESC-SRF as a foundation upon which they can build their own complementary sovereignty criteria and controls when using the AWS European Sovereign Cloud.

To clearly explain how the AWS European Sovereign Cloud meets sovereignty expectations, we’re publishing the ESC-SRF in AWS Artifact including the criteria and control mapping. In AWS Artifact, our self-service audit artifact retrieval portal, you have on-demand access to AWS security and compliance documents and AWS agreements. You can now use the ESC-SRF to define best practices for your own use case, map these to controls, and illustrate how you meet and even exceed sovereign needs of your customers.

A transparent and validated sovereignty model

The ESC-SRF has been built from customer feedback, regulatory requirements across the European Union (EU), industry frameworks, AWS contractual commitments, and partner input. ESC-SRF is industry and sector agnostic, as it’s written to address fundamental sovereignty needs and expectations at the foundational layer of our cloud offerings with additional sovereignty-specific requirements and controls that apply exclusively to the AWS European Sovereign Cloud. Each criterion is implemented through sovereign controls that will be independently validated by a third-party auditor.

The framework builds on core AWS security capabilities, including encryption, key management, access governance, AWS Nitro System-based isolation, and internationally recognized compliance certifications. The framework adds sovereign-specific governance, technical, and operational measures such as independent EU corporate structures, dedicated EU trust and certificate services, operations by AWS EU-resident personnel, strict residency for customer data and customer created metadata, separation from all other AWS Regions, and incident response operated within the EU.

These controls are the basis of a dedicated AWS European Sovereign Cloud System and Organization Controls (SOC) 2 attestation. The ESC-SRF establishes a solid foundation for sovereignty of the cloud, so that customers can focus on defining sovereignty measures in the cloud that are tailored to their goals, regulatory needs, and risk posture.

How you can use the ESC-SRF

The ESC-SRF describes how AWS implements and validates sovereignty controls in the AWS European Sovereign Cloud. AWS treats each criterion as binding and its implementation will be validated by an independent third-party auditor in 2026. While most customers don’t operate at the size and scale of AWS, you can use the ESC-SRF as both an assurance model and a reference framework you can adapt to your specific use cases.

From an assurance perspective, it provides end-to-end visibility for each sovereignty criterion through to its technical implementation. We will also provide third-party validation in the AWS European Sovereign Cloud SOC 2 report. Customers can use this report with internal auditors, external assessors, supervisory authorities, and regulators. This can reduce the need for ad-hoc evidence requests and supports customers by providing them with evidence to demonstrate clear and enforceable sovereignty assurances.

From a design perspective, you can refer to the framework when shaping your own sovereignty architecture, selecting configurations, and defining internal controls to meet regulatory, contractual, and mission-specific requirements. Because the ESC-SRF is industry and sector agnostic, you can apply criteria from the framework to suit your own unique needs. Depending on your sovereign use case, not all criteria may apply to your use case sovereign needs. The ESC-SRF can also be used in conjunction with AWS Well-Architected which can help you learn, measure, and build using architectural best practices. Where appropriate you can create your version of the ESC-SRF, map to controls, and have them tested by a third party. To download the ESC-SRF, visit AWS Artifact (login required).

A strong, clear foundation

The publication of the ESC-SRF is part of our ongoing commitment to delivering on the AWS Digital Sovereignty Pledge through transparency and assurances to help customers meet their evolving sovereignty needs with assurances designed, implemented, and validated entirely within the EU. Within the framework, customers can build solutions in the AWS European Sovereign Cloud with confidence and a strong understanding of how they are able to meet their sovereignty goals using AWS.

For more information about the AWS European Sovereign Cloud, visit aws.eu.


If you have feedback about this post, submit comments in the Comments section below.

Andreas Terwellen

Andreas Terwellen

Andreas is a Senior Manager in security audit assurance at AWS, based in Frankfurt, Germany. His team is responsible for third-party and customer audits, attestations, certifications, and assessments across Europe. Previously, he was a CISO in a DAX-listed telecommunications company in Germany. He also worked for various consulting companies managing large teams and programs across multiple industries and sectors.

Pop!_OS 24.04 LTS released

Post Syndicated from jzb original https://lwn.net/Articles/1050129/

Version 24.04 LTS of the Ubuntu-based Pop!_OS distribution has
been released
with the COSMIC Desktop Environment:

Today is special not only in that it’s the culmination of over
three years of work, but even more so in that System76 has built a
complete desktop environment for the open source community. We’re
proud of this contribution to the open source ecosystem. COSMIC is
built on the ethos that the best open source projects enable people to
not only use them, but to build with them. COSMIC is modular and
composable. It’s the flagship experience for Pop!_OS in its own way,
and can be adapted by anyone that wants to build their own unique user
experience for Linux.

In addition to the COSMIC desktop environment, Pop!_OS is now
available for Arm computers with the 24.04 LTS release, and the
distribution has added hybrid graphics support for better battery
life. LWN covered an
alpha version of COSMIC in August 2024.

[$] Toward a policy for machine-learning tools in kernel development

Post Syndicated from corbet original https://lwn.net/Articles/1049830/

The first topic of discussion at the 2025 Maintainers Summit has been in
the air for a while: what role — if any — should machine-learning-based
tools have in the kernel development process? While there has been a fair
amount of controversy around these tools, and concerns remain, it seems
that the kernel community, or at least its high-level maintainership, is
comfortable with these tools becoming a significant part of the development
process.

AIs Exploiting Smart Contracts

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/12/ais-exploiting-smart-contracts.html

I have long maintained that smart contracts are a dumb idea: that a human process is actually a security feature.

Here’s some interesting research on training AIs to automatically exploit smart contracts:

AI models are increasingly good at cyber tasks, as we’ve written about before. But what is the economic impact of these capabilities? In a recent MATS and Anthropic Fellows project, our scholars investigated this question by evaluating AI agents’ ability to exploit smart contracts on Smart CONtracts Exploitation benchmark (SCONE-bench)­a new benchmark they built comprising 405 contracts that were actually exploited between 2020 and 2025. On contracts exploited after the latest knowledge cutoffs (June 2025 for Opus 4.5 and March 2025 for other models), Claude Opus 4.5, Claude Sonnet 4.5, and GPT-5 developed exploits collectively worth $4.6 million, establishing a concrete lower bound for the economic harm these capabilities could enable. Going beyond retrospective analysis, we evaluated both Sonnet 4.5 and GPT-5 in simulation against 2,849 recently deployed contracts without any known vulnerabilities. Both agents uncovered two novel zero-day vulnerabilities and produced exploits worth $3,694, with GPT-5 doing so at an API cost of $3,476. This demonstrates as a proof-of-concept that profitable, real-world autonomous exploitation is technically feasible, a finding that underscores the need for proactive adoption of AI for defense.

React2Shell and related RSC vulnerabilities threat brief: early exploitation activity and threat actor techniques

Post Syndicated from Cloudforce One original https://blog.cloudflare.com/react2shell-rsc-vulnerabilities-exploitation-threat-brief/

On December 3, 2025, immediately following the public disclosure of the critical, maximum-severity React2Shell vulnerability (CVE-2025-55182), the Cloudforce One Threat Intelligence team began monitoring for early signs of exploitation. Within hours, we observed scanning and active exploitation attempts, including traffic originating from infrastructure associated with Asian-nexus threat groups.

Early activity indicates that threat actors quickly integrated this vulnerability into their scanning and reconnaissance routines. We observed systematic probing of exposed systems, testing for the flaw at scale, and incorporating it into broader sweeps of Internet‑facing assets. The identified behavior reveals the actors relied on a combination of tools, such as standard vulnerability scanners and publicly accessible Internet asset discovery platforms, to find potentially vulnerable React Server Components (RSC) deployments exposed to the Internet.

Patterns in observed threat activity also suggest that the actors focused on identifying specific application metadata — such as icon hashes, SSL certificate details, or geographic region identifiers — to refine their candidate target lists before attempting exploitation. 

In addition to React2Shell, two additional vulnerabilities affecting specific RSC implementations were disclosed: CVE-2025-55183 and CVE-2025-55184. Both vulnerabilities, while distinct from React2Shell, also relate to RSC payload handling and Server Function semantics, and are described in more detail below.

Background: React2Shell vulnerability (CVE-2025-55182)

On December 3, 2025, the React Team disclosed a Remote Code Execution (RCE) vulnerability affecting servers using the React Server Components (RSC) Flight protocol. The vulnerability, CVE-2025-55182, received a CVSS score of 10.0 and has been informally referred to as React2Shell.

The underlying cause of the vulnerability is an unsafe deserialization flaw in the RSC Flight data-handling logic. When a server processes attacker-controlled payloads without proper validation, it becomes possible to influence server-side execution flow. In this case, crafted input allows an attacker to inject logic that the server interprets in a privileged context.

Exploitation is straightforward. A single, specially crafted HTTP request is sufficient; there is no authentication requirement, user interaction, or elevated permissions involved. Once successful, the attacker can execute arbitrary, privileged JavaScript on the affected server.

This combination of authenticated access, trivial exploitation, and full code execution is what places CVE-2025-55182 at the highest severity level and makes it significant for organizations relying on vulnerable versions of React Server Components. 

In response, Cloudflare has deployed new rules across its network, with the default action set to Block. These new protections are included in both the Cloudflare Free Managed Ruleset (available to all Free customers) and the standard Cloudflare Managed Ruleset (available to all paying customers), as detailed below. More information about the different rulesets can be found in our documentation.

CVE

Description

Cloudflare WAF Rule ID

CVE-2025-55182

React – RCE

Rules to mitigate React2Shell Exploit

Paid: 33aa8a8a948b48b28d40450c5fb92fba

Free: 2b5d06e34a814a889bee9a0699702280

CVE-2025-55182 – 2

React – RCE Bypass

Additional rules to mitigate exploit bypass

Paid: bc1aee59731c488ca8b5314615fce168

Free: cbdd3f48396e4b7389d6efd174746aff

CVE-2025-55182

Scanner Detection

Additional paid WAF rule to catch React2Shell scanning attempts

Paid: 1d54691cb822465183cb49e2f562cf5c

Recently disclosed RSC vulnerabilities

In addition to React2Shell, two additional vulnerabilities affecting specific RSC implementations were disclosed. The two vulnerabilities, while distinct from React2Shell, also relate to RSC payload handling and Server Function semantics, with corresponding Cloudflare protections noted below:

CVE

Description

Cloudflare WAF Rule ID

CVE-2025-55183

Leaking Server Functions

In deployments where Server Function identifiers are insufficiently validated, an attacker may force the server into returning the source body of a referenced function

Paid: 17c5123f1ac049818765ebf2fefb4e9b

Free: 3114709a3c3b4e3685052c7b251e86aa

CVE-2025-55184

React Function DoS

A crafted RSC Flight Payload containing cyclical Promise references can trigger unbounded recursion or event-loop lockups under certain server configurations, resulting in denial-of-service conditions

Paid: 2694f1610c0b471393b21aef102ec699

Investigation of early scanning and exploitation

The following analysis details the initial wave of activity observed by Cloudforce One, focusing on threat actor attempts to scan for and exploit the React2Shell vulnerability. While these findings represent activity immediately following the vulnerability’s release, and were focused on known threat actors, it is critical to note that the volume and scope of related threat activity have expanded dramatically since these first observations.

Tactics

Unsurprisingly, the threat actors were relying heavily on publicly available, commercial, and a variety of other tools to identify vulnerable servers:

  • Vulnerability intelligence: The actors leveraged vulnerability intelligence databases that aggregated CVEs, advisories, and exploits for tracking and prioritization.

  • Vulnerability reconnaissance: The actors conducted searches using large-scale reconnaissance services, indicating they are relying on Internet-wide scanning and asset discovery platforms to find exposed systems running React App or RSC components. They also made use of tools that identify the software stack and technologies used by websites.

  • Vulnerability scanning: Activity included use of Nuclei (User-Agent: Nuclei – CVE-2025-55182), a popular rapid scanning tool used to deploy YAML-based templates to check for vulnerabilities. The actors were also observed using a highly likely React2Shell scanner associated with the User-Agent “Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 React2ShellScanner/1.0.0“.

  • Vulnerability exploitation: The actors made use of Burp Suite, a web application security testing platform for identifying and exploiting vulnerabilities in HTTP/S traffic.

Techniques 

Recon via Internet-wide scanning and asset discovery platform 
To enumerate potential React2Shell targets, the actors leveraged an Internet-wide scanning and asset-discovery platform commonly used to fingerprint web technologies at scale. Their queries demonstrated a targeted effort to isolate React and Next.js applications — two frameworks directly relevant to the vulnerability — by searching for React-specific icon hashes, framework-associated metadata, and page titles containing React-related keywords. This approach likely allowed them to rapidly build an inventory of exploitable hosts before initiating more direct probing.

Targeting enumeration and filtering 
During their reconnaissance phase, the operators applied additional filtering logic to refine their target set and minimize noise. Notably, they excluded Chinese IP space from their searches, indicating that their enumeration workflow intentionally avoided collecting data on possibly domestic infrastructure. They also constrained scanning to specific geographic regions and national networks to identify likely high-value hosts. Beyond basic fingerprinting, the actors leveraged SSL certificate attributes — including issuer details, subject fields, and top-level domains — to surface entities of interest, such as government or critical-infrastructure systems using .gov or other restricted TLDs. This combination of geographic filtering and certificate-based pivoting enabled a more precise enumeration process that prioritized strategically relevant and potentially vulnerable high-value targets.

Preliminary target analysis
Observed activity reflected a clear focus on strategically significant organizations across multiple regions. Their highest-density probing occurred against networks in Taiwan, Xinjiang Uygur, Vietnam, Japan, and New Zealand — regions frequently associated with geopolitical intelligence collection priorities. Other selective targeting was also observed against entities across the globe, including government (.gov) websites, academic research institutions, and critical‑infrastructure operators. These infrastructure operators specifically included a national authority responsible for the import and export of uranium, rare metals, and nuclear fuel.

The actors also prioritized high‑sensitivity technology targets such as enterprise password managers and secure‑vault services, likely due to their potential to provide downstream access to broader organizational credentials and secrets. 

Additionally, the campaign targeted edge‑facing SSL VPN appliances whose administrative interfaces may incorporate React-based components, suggesting the actor sought to exploit React2Shell against both traditional web applications and embedded web management frameworks in order to maximize access opportunities.

Early threat actor observations
Cloudforce One analysis confirms that early scanning and exploitation attempts originated from IP addresses previously associated with multiple Asia-affiliated threat actor clusters.  While not all observed IP addresses belong to a single operator, the simultaneous activity suggests shared tooling, infrastructure, or experimentation in parallel among groups with a common purpose and shared targeting objectives. Observed targeting enumeration and filtering (e.g. a focus on Taiwan and Xinjiang Uygur, but exclusion of China), as well as heavy use of certain scanning and asset discovery platforms, suggest general attribution to Asia-linked threat actors.

Overall trends

Cloudflare’s Managed Rulesets for React2Shell began detecting significant activity within hours of the vulnerability’s disclosure. The graph below shows the daily hit count across the two exploit-related React2Shell WAF rules. 


Aggregate rule hit volume over time

The React2Shell disclosure triggered a surge of opportunistic scanning and exploit behavior. In total, from 2025-12-03 00:00 UTC to 2025-12-11 17:00UTC, we received 582.10M hits. That equates to an average of 3.49M hits per hour, with a maximum number of hits in a single hour reaching 12.72M. The average unique IP count per hour was 3,598, with the maximum number of IPs in an hour being 16,585.


Hourly count of unique IPs sending React2Shell-related probes 

Our data also shows distinct peaks above 6,387 User-Agents per hour, indicating a heterogeneous mix of tools and frameworks in use, with the average number of unique User-Agents per hour being 2,255. The below graph shows exploit attempts based on WAF rules (Free and Managed) triggering on matching payloads:


Unique User-Agent strings used in React2Shell-related requests

To better understand the types of automated tools probing for React2Shell exposure, Cloudflare analyzed the User-Agent strings associated with React2Shell-related requests since December 3, 2025. The data shows a wide variety of scanning tools suggesting broad Internet-wide reconnaissance: 

Top 10 User Agent strings by exploit attempts

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 Assetnote/1.0.0

Block Security Team/Assetnote-HjJacErLyq2xFe01qaCM1yyzs

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 (GIS – AppSec Team – Project Vision)

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36

python-requests/2.32.5

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 Assetnote/1.0.0 (ExposureScan)

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/142.0.0.0 Safari/537.36

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36

Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/18.1 Safari/605.1.1

Payload variation and experimentation

Cloudflare analyzed the payload sizes associated with requests triggering React2Shell-related detection rules. The long-tailed distribution — dominated by sub-kilobyte probes, but punctured by extremely large outliers — suggest actors are testing a wide range of payload sizes:

Metric

Value

Maximum payload size

375 MB

Average payload size

3.2 KB

p25 (25th Percentile)

703 B

p75 (75th Percentile)

818 B

p90 (90th Percentile)

2.7 KB

p99 (99th Percentile)

66.5 KB

Standard deviation

330 KB

Additional React vulnerabilities identified 

In parallel with our ongoing analysis of the React2Shell vulnerability, two additional vulnerabilities affecting React Server Components (RSC) implementations have been identified:

1. React function DoS

The vulnerability CVE-2025-55184 was recently disclosed, revealing that React Server Component frameworks can be forced into a Node.js state where the runtime unwraps an infinite recursion of nested Promises.

This behavior:

  • Freezes the server indefinitely

  • Prevents yielding back to the event loop

  • Effectively takes the server offline

  • Does not require any specific Server Action usage — merely the presence of a server capable of processing an RSC Server Action payload 

The trigger condition is a cyclic promise reference inside the RSC payload.

2. Leaking server functions 

Another vulnerability, CVE-2025-55183, was also recently disclosed, revealing that certain React Server Component frameworks can leak server-only source code under specific conditions.

If an attacker gains access to a Server Function that:

  • Accepts an argument that undergoes string coercion, and

  • Does not validate that the argument is of an expected primitive type

then the attacker can coerce that argument into a reference to a different Server Function. The coerced value’s toString() output causes the server to return the source code of the referenced Server Function.

How Cloudflare is protecting customers

Cloudflare’s protection strategy is multi-layered, relying on both the inherent security model of its platform and immediate, proactive updates to its Web Application Firewall (WAF). 

  • Cloudflare Workers: React-based applications and frameworks deployed on Cloudflare Workers are inherently immune. The Workers security model prevents exploits from succeeding at the runtime layer, regardless of the malicious payload.

  • Proactive WAF deployment: Cloudflare urgently deployed WAF rules to detect and block traffic proxied through its network related to React2Shell and the recently disclosed RSC vulnerabilities.   

The Cloudflare security team continues to monitor for additional attack variations and will update protections as necessary to maintain continuous security for all proxied traffic. 

Continuous monitoring 

While Cloudflare’s emergency actions — the WAF limit increase and immediate rule deployment — have successfully mitigated the current wave of exploitation attempts, this vulnerability represents a persistent and evolving threat. The immediate weaponization of CVE-2025-55182 by sophisticated threat actors underscores the need for continuous defense.

Cloudflare remains committed to continuous surveillance for emerging exploit variants and refinement of WAF rules to detect evasive techniques. However, network-level protection is not a substitute for remediation at the source. Organizations must prioritize immediate patching of all affected React and Next.js assets. This combination of platform-level WAF defense and immediate application patching remains the only reliable strategy against this critical threat.

Indicators of Compromise

Tool/Scanner

User Agent String

Observation/Purpose

Nuclei

Nuclei – CVE-2025-55182

User-Agent for rapid, template-based scanning for React2Shell vulnerability

React2ShellScanner

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 React2ShellScanner/1.0.0

User-Agent for a likely custom React2Shell vulnerability scanner

Architecting conversational observability for cloud applications

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/architecture/architecting-conversational-observability-for-cloud-applications/

Modern cloud applications are commonly built as a collection of loosely coupled microservices running on services like Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Container Service (Amazon ECS), or AWS Lambda. This architecture gives engineering teams flexibility and scalability, but its inherently distributed nature also makes troubleshooting more difficult. When something breaks, engineers often find themselves digging through logs, events, and metrics scattered across different observability layers. With Kubernetes, for example, without a deep understanding of the service, troubleshooting can turn into a time-consuming effort to manually correlate information from different sources.

In this post, we walk through building a generative AI–powered troubleshooting assistant for Kubernetes. The goal is to give engineers a faster, self-service way to diagnose and resolve cluster issues, cut down Mean Time to Recovery (MTTR), and reduce the cycles experts spend finding the root cause of issues in complex distributed systems.

Overview

One of the challenges of architecting a modern cloud application is keeping observability intact across many moving pieces. Anyone who has ever tailed logs in one terminal while running kubectl describe and curl commands in another, knows how tedious this can get. Distributed systems are powerful, but they’re also complex. Kubernetes, for example, offers strong orchestration capabilities, yet troubleshooting inside a cluster often means navigating multiple layers of abstractions such as pods, nodes, networking, logs, and events. On top of that, the system generates a large volume of telemetry, including kubelet logs, application logs, cluster events, and metrics. Making sense of these layers requires both expertise on the system and application knowledge.

This skill gap shows up in the numbers. According to the 2024 Observability Pulse Report, 48% of organizations say that lack of team knowledge is their biggest challenge to observability in cloud-native environments. MTTR has also been going up for three years straight, with most teams (82%) saying it can take more than an hour to resolve production issues.

When something goes wrong and your applications start to fail for an unknown reason, engineers often must start stitching together signals from multiple sources to find the root cause. That can be tedious for specialists, and it gets worse when the issue is intermittent or spans across services. Often, multiple teams need to get involved – application engineers may not know Kubernetes well, while platform teams may not have deep insight into the applications. This can result in longer troubleshooting cycles, potentially degraded user experience, and pulling engineers away from planned work that drives business goals.

Figure 1. A multitude of telemetry sources in Kubernetes clusters
This is where generative artificial intelligence (AI) can help. Users can build an AI assistant that combines large language model (LLM)-driven analysis and guidance with existing telemetry data. This assistant enables engineers to troubleshoot issues faster, in a self-service way, without requiring every team to become Kubernetes experts. In the following sections, we show how to build such an assistant for Amazon EKS, however, keep in mind that a similar approach can be extended to other compute services like Amazon ECS or AWS Lambda.

Solution architecture

Architecting this AI-powered troubleshooting assistant consists of three primary parts:

  • Deployment approach selection: The solution supports two architectures – a traditional Retrieval-Augmented Generation (RAG)-based chatbot and a modern Strands-based agentic system that uses the Strands Agents SDK with EKS MCP Server integration for direct EKS API access.
  • Telemetry collection and storage: Collecting telemetry from various sources and storing it as vector embeddings in Amazon OpenSearch (RAG approach) or as 1024-dimensional embeddings in Amazon S3 Vectors (Strands approach).
  • Interactive troubleshooting interface: Building either a web-based chatbot that retrieves relevant telemetry and injects it into LLM prompts, or a Slack integrated multi-agent system that uses MCP tools for real-time Kubernetes diagnostics.

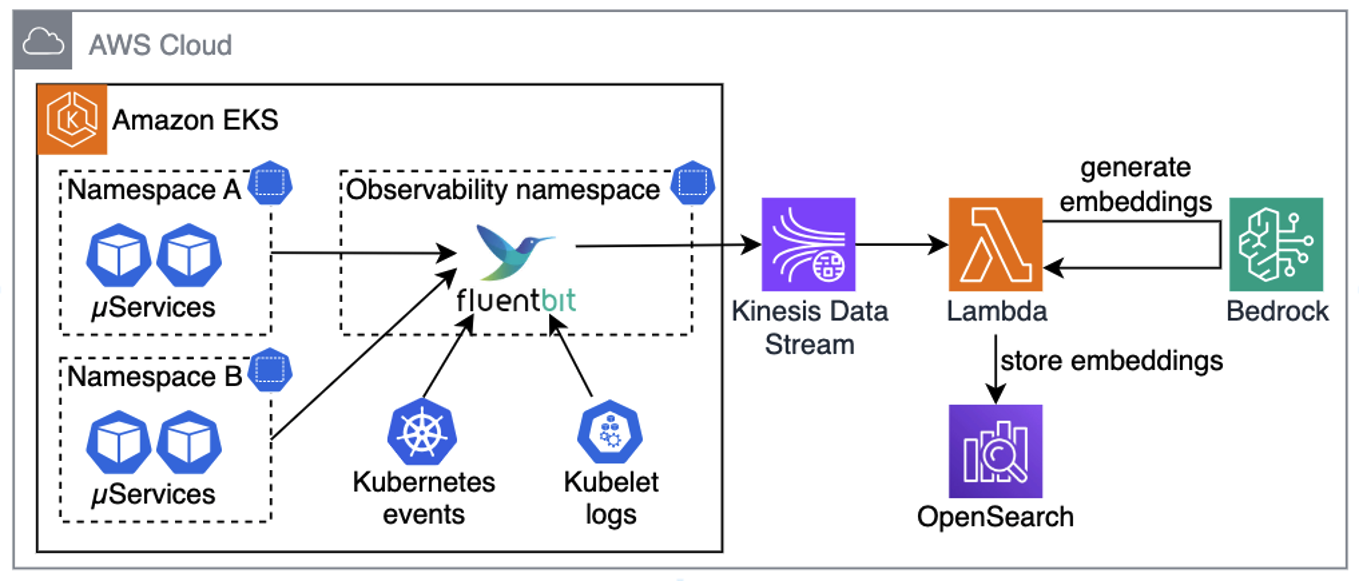
For this architecture walkthrough, we focus on the RAG-based approach. The first step is setting up a pipeline that can reliably collect, process, and store telemetry data. This pipeline aggregates telemetry from the relevant data sources, such as application logs, kubelet logs, and Kubernetes events. In Kubernetes environments, this can be done with a telemetry processor and forwarder, such as Fluent Bit, which streams telemetry into Amazon Kinesis Data Streams. On the receiving end, we use a Lambda function to normalize collected data, Amazon Bedrock to generate vector embeddings, and OpenSearch Serverless to store this embedded representation for efficient retrieval. Because these services are serverless, we can avoid the overhead of managing infrastructure and can focus on the troubleshooting workflow itself.

Figure 2. Collecting telemetry from sources, generating embeddings, and saving in OpenSearch
Pro tip: for better performance and cost-efficiency, your Lambda functions should use batching when ingesting data from Kinesis, generating embeddings, and storing them in OpenSearch.

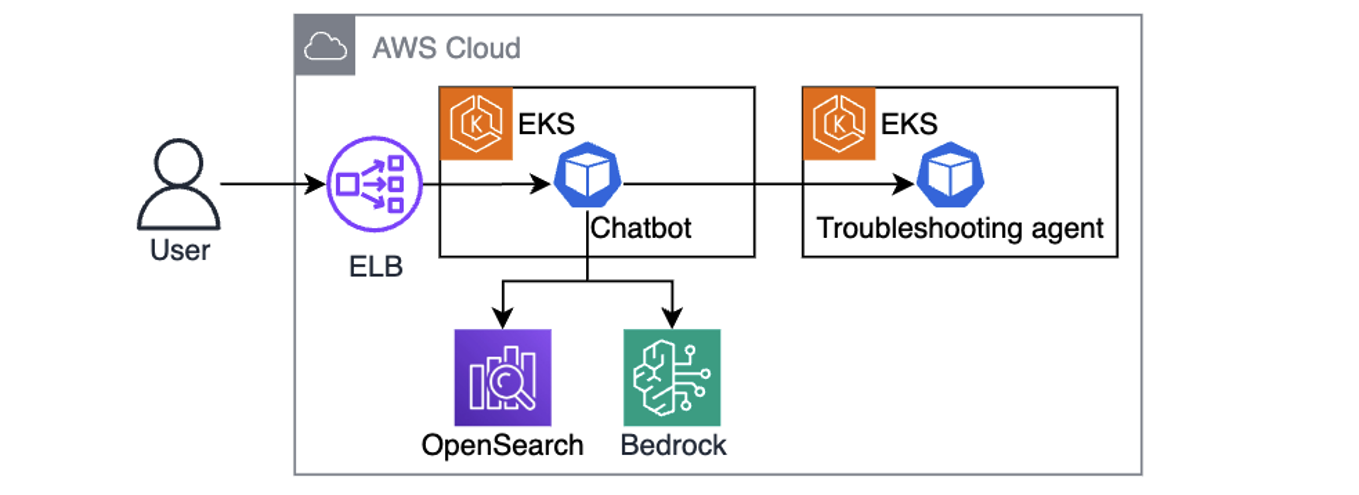
Once telemetry is collected, converted to embeddings, and stored in OpenSearch, the next step is building a chatbot that uses RAG. Using RAG means that when a user asks a question, the chatbot looks up semantically similar telemetry in OpenSearch, adds it to the prompt, and sends it to the LLM. Instead of generic answers, the model now has relevant telemetry and cluster-specific details it can use to generate useful next steps, such as precise kubectl commands for the troubleshooting assistant, as illustrated in the following diagram.

Figure 3. Chatbot is using user queries augmented with telemetry context to send kubectl commands to the troubleshooting assistant. 
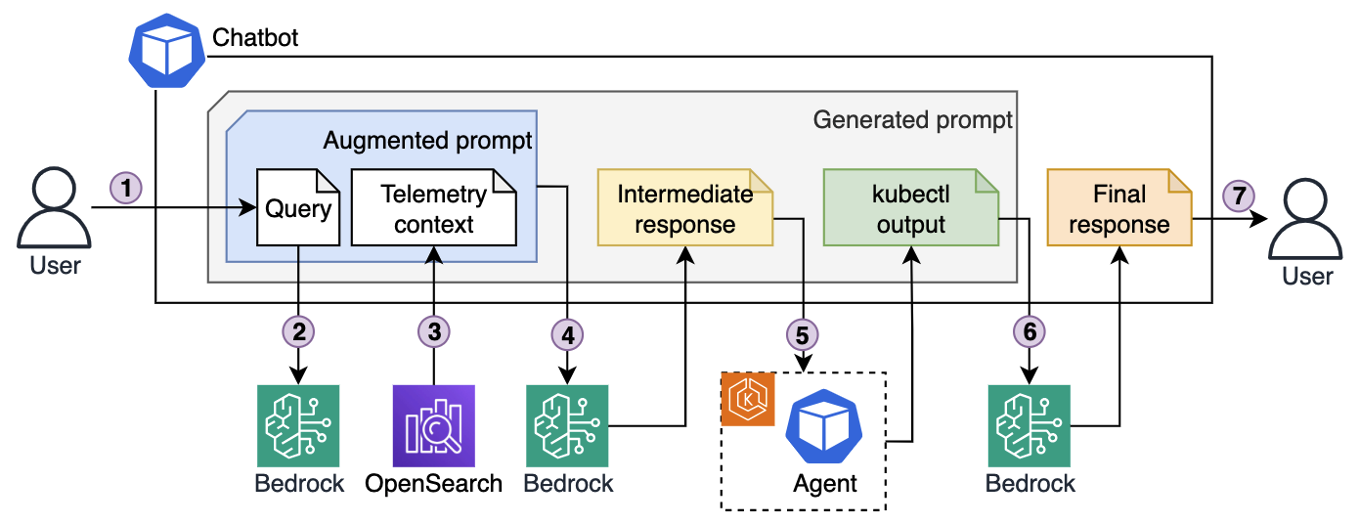
One powerful aspect of this design is its iterative nature. The chatbot hands instructions to a troubleshooting assistant running in the cluster, which executes a set of allowlisted, read-only kubectl commands. The output comes back to the LLM, which can decide whether it needs to investigate further (by asking the troubleshooting assistant to run more kubectl commands), or present a clear resolution path to the engineer. This cycle gradually builds a richer picture of the issue by combining historical telemetry with real-time cluster state to speed up root cause analysis.

Figure 4. Iterative troubleshooting process.
Here’s the end-to-end troubleshooting flow illustrated in the preceding diagram:

  1. An engineer enters a query into the chatbot interface, for example “My pod is stuck in pending state. Investigate.”
  2. The chatbot sends the query to Bedrock, which converts it into vector embeddings.
  3. Using those embeddings, the chatbot retrieves semantically matching telemetry that was previously stored in OpenSearch.
  4. The chatbot generates an augmented prompt, which contains both the original query and semantically relevant telemetry, and passes it to the LLM. The LLM responds with a list of kubectl commands to run for further diagnostics.
  5. The chatbot forwards those commands to the troubleshooting assistant running in the EKS cluster. The agent executes them with a service account that has read-only permissions, following the principle of least privilege, and sends the output back.
  6. Based on the output, the chatbot asks LLM to decide whether to continue investigation (by asking the agent to run more commands), or whether it has enough context to produce an answer.
  7. Once enough information has been gathered (investigation concluded), the chatbot composes a final prompt, including the query, telemetry, and investigation results, and asks the LLM for a final resolution, which it then returns to the engineer.

Example implementation

Use the example repo to deploy the solution in your AWS account. Follow the instructions in README.md for provisioning and testing the sample project using Terraform. Resources provisioned by the example project incur costs in your AWS account. Make sure to clean up the project as described in the README.md to avoid unexpected costs.

The repository provides two deployment architectures controlled by the deployment_type Terraform variable:

  1. RAG-based deployment (default): See the ./terraform/modules directory for the “ingestion-pipeline” module that creates a Kinesis Data Stream and Lambda function to generate embeddings using "amazon.titan-embed-test-v2:0" and store them in OpenSearch. The “agentic-chatbot” module handles the Gradio web interface and kubectl command execution.
  2. Strands agentic deployment: this approach uses the Strands Agents SDK to create a multi-agent system with three specialized agents:
    1. Agent Orchestrator: Coordinates troubleshooting workflows
    2. Memory Agent: Manages conversation context and historical insights
    3. K8s Specialist: Handles Kubernetes diagnostics

The agentic system stores knowledge as 1024-dimensional embeddings in Amazon S3 Vectors, providing cost-optimized vector storage for AI agents. EKS MCP Server integration enabled direct EKS API access through standardized MCP tools located in ./apps/agentic-troubleshooting/src/tools/. Engineers interact via Slack bot integration, where the Strands agents can execute kubectl commands through the MCP protocol while maintaining Pod Identity security for AWS service access.

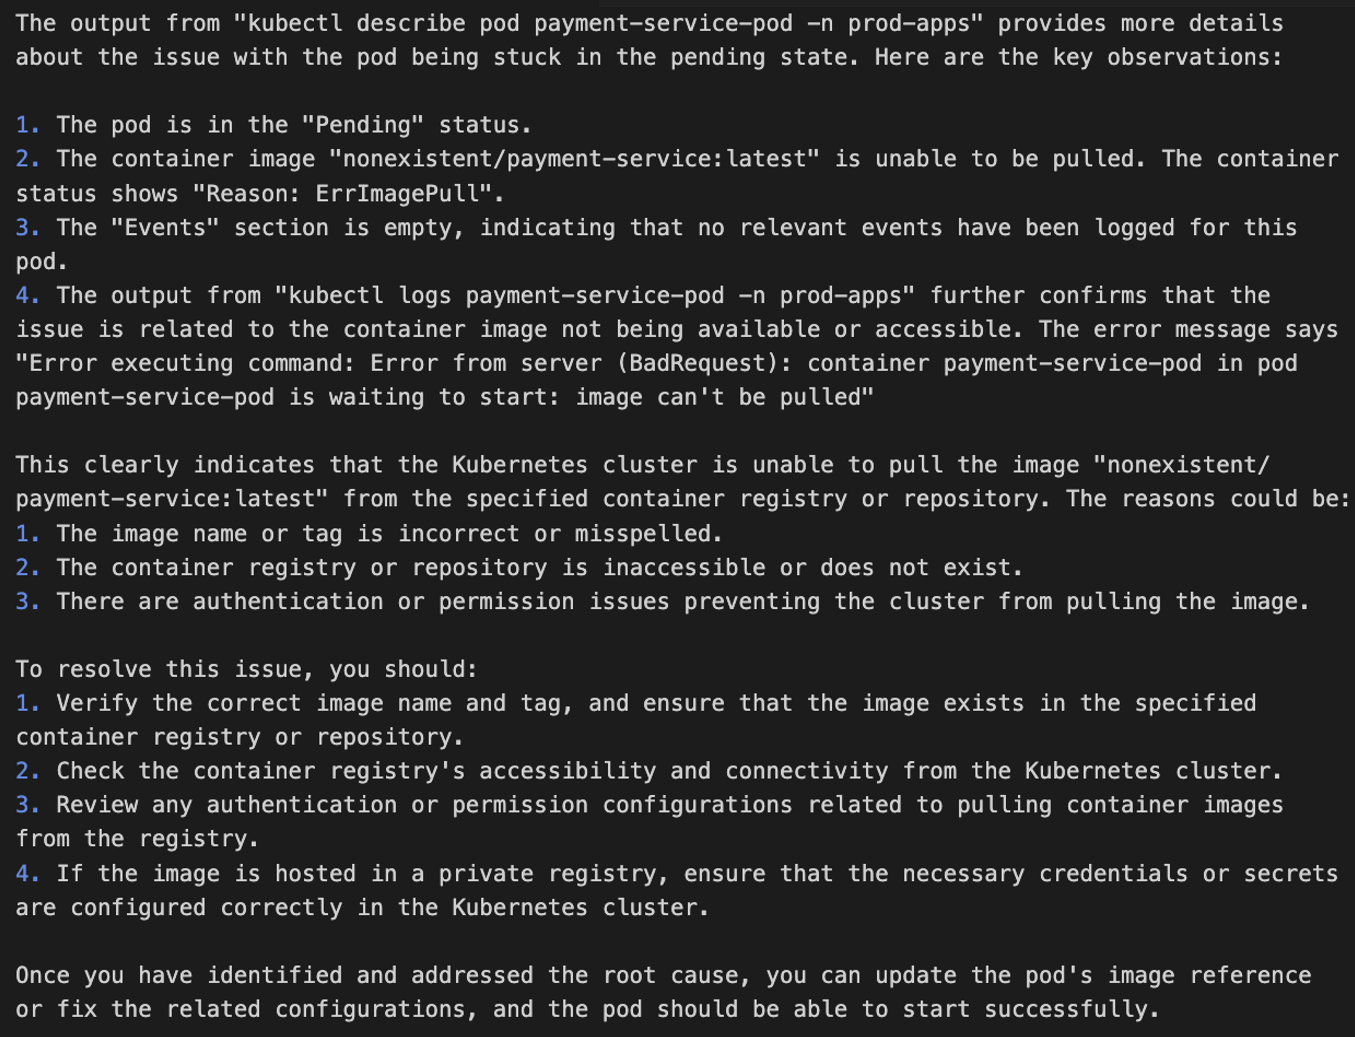
The following screenshot shows an example chatbot response to a query about a pod being stuck in pending state. The assistant generated and ran multiple kubectl commands to build the output and came up with recommendations for issue remediation.

Figure 5. EKS cluster troubleshooting, example output

See AWS re:Invent 2025 – Streamline Amazon EKS operations with Agentic AI and KubeCon – From Logs To Insights: Real-time Conversational Troubleshooting for Kubernetes with GenAI sessions for a deeper dive into solution implementation.

Security considerations

When implementing AI agents for Kubernetes environments, security must be a primary consideration throughout the architecture. The solution requires secure communication channels between the chatbot and EKS clusters, with interactions authenticated through AWS Identity and Access Management (AWS IAM) roles.

Permissions-wise, command execution security is critical. Implementing strict allowlists that only allow read-only kubectl operations to help prevent unauthorized cluster modifications while maintaining diagnostic capabilities. The troubleshooting assistant should also operate with minimal Kubernetes RBAC permissions, limited to viewing pods, services, events, and logs within specific namespaces.

Data protection measures must include sanitizing application logs before embedding generation to help prevent sensitive information exposure, encrypting the telemetry data in transit through Kinesis and at rest in OpenSearch using AWS Key Management Service (AWS KMS).

Follow the AWS Well-Architected Framework Security Pillar principles, deploy components within Amazon Virtual Private Cloud (Amazon VPC) using private subnets and VPC endpoints to minimize network exposure, implement comprehensive logging of troubleshooting activities for audit purposes, and validate user inputs to protect against prompt injection attacks that could manipulate the AI assistant’s behavior.

Conclusion

In this post, we walked through how to architect a generative AI-powered troubleshooting assistant that gives engineers a way to solve Kubernetes issues in a self-service way, without always needing service experts to step in. By combining telemetry analysis with AI-driven context, engineers can get to the root causes faster and keep MTTR low. Assistant’s ability to pull from multiple telemetry sources, run safe diagnostic commands, and provide actionable recommendations helps to make the troubleshooting process more efficient and less disruptive to ongoing work.

As distributed systems continue to grow in scale and complexity, solutions like the one described in this post become essential. Putting AI on top of your observability data helps to practically handle these challenges today, while also setting you up for more autonomous, resilient operations in the future.

Мила родино, ти си ергенски рай

Post Syndicated from Светла Енчева original https://www.toest.bg/mila-rodino-ti-si-ergenski-ray/

Мила родино, ти си ергенски рай

Първият сезон на „Ергенът: Любов в рая“ вече е минало. Човек може да гледа риалити шоута по различни причини. Например за да изпитва морално или естетическо превъзходство, да се подиграва, да се възмущава, да се вживява в екранни драми, да си намира повод да влиза в пререкания или просто да си убива времето. Може да гледа обаче и за да разбере – какви ценности и послания се внушават, как се „управляват“ постъпките на участниците и зрителските реакции, какво ни казва шоуто за обществото, в което живеем.

Що се отнася до авторката на настоящата статия – оправдавах своето guilty pleasure (гузно удоволствие) да си причинявам риалитито с обещание, което лекомислено дадох на редакцията на „Тоест“: че след първата си статия по темата съм съгласна да напиша и втора, когато сезонът свърши. Но колкото повече гледах, толкова повече „Ергенът: Любов в рая“ ми заприличваше на държавата, в която живеем.

Задкулисие, което вече не се крие

В България отдавна се говори за задкулисие – реална власт извън формалното управление, която „дърпа конците“ на държавата. През 2009 г. репликата на Ахмед Доган „Аз разпределям порциите на властта“ от изтекъл запис с негово участие на събитие на ДПС звучеше скандално. Днес #кой дърпа конците, отдавна не е тайна.

Задкулисието в ергенския рай е Продукцията – с главна буква, защото е самостоятелен герой със собствена роля. По принцип се очаква една продукция да е по-скоро невидима, освен в специални моменти, като церемонии, за да изглежда, че отношенията между участниците следват естествен ход. Нашата Продукция обаче се намесва, когато и както реши.

Под формата на глас зад кадър например Продукцията внушава на ергенка чувство за вина, защото върши нормалното за участниците в подобно риалити – колебае се в чувствата си към ерген, с когото се е запознала наскоро, и казва ту че не го харесва, ту че го харесва. В резултат ергенката цяла седмица плаче, тръшка се, че е виновна, и напомня „вината“ си дори в самия край на шоуто.

По аналогичен начин в България хора биват пречупвани и принудени да подпишат самопризнания под натиск, като бившия заместник на Коцев – Диан Иванов.

Властта на задкуслисието води до произволно прилагане на правилата.

Основно правило в ергенския рай е, че който не получи роза, си тръгва, освен ако водещата не му даде една от общо трите за цялото предаване спасителни златни рози. Един ерген обаче се колебае между две ергенки. Дава роза на едната, другата си тръгва и той се разкайва за избора си. Но не щеш ли, кахърният мъж кани на среща отхвърлената участничка, моли я да се върне и тя се съгласява. Как става тази работа, след като ергенката вече е напуснала предаването, без дългата ръка на Продукцията?

Но какво ли се учудваме – колко институции в България са оглавявани от хора, чийто мандат вече е изтекъл? Членове на регулатори, на Висшия съдебен съвет, директорът на БНТ… Най-очеизбождащият пример е с главния прокурор. Въпреки че съдът „не даде роза“ на Борислав Сарафов, постановявайки, че той е нелегитимен главен прокурор, засега нищо не може да го мръдне от поста.

Като стана дума за мандати, първоначалното впечатление за джендърната „мандатност“ в шоуто беше, че на една церемония жените дават рози на мъжете, а на следващата е обратното. В един период обаче имаше три поредни церемонии, в които мъжете даваха рози на жените. Защо? Ергенките все бяха повече. Кой обаче решава в „рая“ да влизат повече жени, отколкото мъже, ако не Продукцията?

В някои случаи произволните решения на Продукцията са обясними с гоненето на рейтинг. Например тя отне правото на избор на ергенка, която показваше колебание между двама ергени, като прати и тримата директно на финал – за да има интрига до самия край. По този начин удължи с няколко дни терзанията им, както и тормоза върху участничката. Но и това едва ли ни учудва – колко често в България законодателни решения се приемат след формални или предварително нагласени „обществени обсъждания“, без да се чуе гласът на хората, които те засягат?

С напредването на риалитито Продукцията все повече ставаше тема на разговор между ергените. Един от членовете на пратения на финал любовен триъгълник дори конкретно я визира, обосновавайки решението си да остане, вместо да си тръгне:

Просто напук и на инат, защото всички ме дразните. И искам и на вас да ви е гадно с мене. И на Продукцията.

Милиони, закони, кокошки, прошки и Ново начало

Понякога действията на Продукцията трудно могат да се оправдаят с рейтинга и сценария, а зад тях прозира неравно третиране на участниците.

В една игра ергените мъже трябва да се състезават по двойки в дърпане на въже. Няма предварително зададени правила как точно да се удържи въжето. Единият от двамата финалисти не разчита само на грубата си мъжка сила, а прилага тактика, с която побеждава. Това поражда възмущение сред участниците (макар той да не е единственият участник в играта, приложил подобна тактика). Продукцията предлага на ергенките да гласуват кой е победил, и те избират загубилия битката.

Ако отново потърсим паралели с обществения живот в България, няма да ни е трудно да открием такива. Ето, Конституционният съд и Върховният касационен съд сътвориха тълкувания на понятията за пол и традиции в Конституцията, каквито в Основния закон няма, само и само служебно да декласират групата на ЛГБТ хората.

Отвръщайки на канонадата от упреци, че не е спазил правилата (каквито е нямало), спечелилият с тактика и впоследствие служебно загубил ерген обръща внимание върху едно доста по-сериозно неспазване на правила. А именно, че

ергени са излезли да се почерпят извън района, в който се снима предаването.

Напускането на „рая“ е забранено и тъй като всичко се снима с камери, то не би могло да се осъществи без благословията на Продукцията.

„Бегълците“, които са сред най-яростните обвинители на декласирания ерген, не показват никакво притеснение, когато става ясно, че са нарушили едно от най-важните правила. Напротив, хвалят се колко хубаво са си изкарали и как са пили „шотчета“. На въпроса дали има привилегии, един от тях отговори:

Имам, да! В песента се пее: „За кокошка няма прошка, за милиони няма закони“! Кое не ти е ясно?

Със споменаването на известната поговорка ергенът нямаше предвид обичайния ѝ смисъл – изтъкване на социална несправедливост. Напротив, изразяваше гордост, тъй като самият той твърди, че е милионер. Един вид, полага му се да е над законите.

Над правилата е и ергенката, която беше кандидат-депутатка от ДПС – Ново начало на изборите на 27 октомври 2025 г.

В качеството си на половинка в „рая“ на ергена с милионите и тя е от пилите „шотчета“ извън района на снимките. Но това май не е единствената ѝ привилегия.

Едно от основните правила за участниците е, че те нямат право да използват телефоните си. Мобилните им устройства се вземат преди началото на снимките и им се връщат след финала. На кадър от предаването (на 25-тата секунда от това видео) обаче се вижда как ергенката от „Ново начало“ държи нещо, което има формата на телефон и свети като телефон. Ако следваме принципа, че най-простото обяснение често е вярното, това най-вероятно е мобилен телефон.

(Не)толерантност към насилието

Случаите на вербално насилие в „рая“, на тормоз, подигравки, обиди заради външния вид (т.нар. бодишейминг), унижаване и пр. са толкова много, че и няколко статии няма да стигнат за споменаването им. Физическото насилие обаче е забранено, научаваме от разговори на Продукцията с участници. Това правило беше моментално приложено за едва-що влязъл в шоуто ерген, който събори ергенка от стола ѝ. Сцената не беше излъчена изцяло в предаването, а само загатната, както е и редно, защото показването на насилието на екран го мултиплицира.

Аналогична би следвало да е реакцията и ако ергенка бутне друга в басейна. Но не е. Бутането в басейна е задача, която Продукцията дава в рамките на игра, която уж би трябвало да е забавна за всички. Задачата е възложена на ергенка, изпитваща ревност към друга, в момент, в който почти всички участници тормозят другата. Ревнивата ергенка блъска съперницата си с всички сили. След кратък полет момичето пада във водата. Кадърът с блъскането и полета се повтаря няколко пъти (няма да сложа линк, защото е унизително). Ергените се смеят. „Дано може да плува“, чува се развеселен глас. Момичето излиза от водата и сяда мокро до останалите, защото е длъжно да продължи участието си в играта.

За да направим връзка с обществения живот в България – има групи хора, насилието върху които остава без последствия и дори се толерира. Бежанци се задържат, ограбват и бият на границата; „ловци на бежанци“ се обявяват за герои; събарят се единствените жилища на роми и пр. – държавата внушава, че представителите на някои групи си го „заслужават“.

За ергенки и ергени, които налитат на бой, няма никакви последствия – щом не се е стигнало до реално нанасяне на удари, за Продукцията, изглежда, няма проблем. И някои „дребни“ форми на физическо насилие не се броят. Ерген постепенно засилва агресията си към друг – от вербален тормоз минава към блъскане на краката му с чекмедже. Продукцията го изгонва чак след като изплюва храна върху набелязаната жертва. За разлика от първия изгонен ерген, който ни се чу, ни се видя, този гордо дефилира по bTV, защитавайки гледната си точка.

Тук стигаме до темата за домашното насилие,

понеже вторият изгонен ерген си имаше половинка в „рая“. Забраняваше на избраницата си да говори с другите мъже в шоуто, както и на тях да общуват с нея. Изобщо, смяташе, че е най-добре тя да мълчи, а той да говори вместо нея. И тя преобладаващо си мълчеше, говореше основно в негово отсъствие, почти няма и синхрони с нея (реплики в разговор с Продукцията).

Когато Продукцията реши да изгони ергена, тя му даде възможност преди напускането си да говори и с участника, върху когото беше изплюл храна (уж да му се извини, но на практика не стана точно така), и с избраницата си. Нея той постави пред избор – да си тръгне с него или да остане. На практика обаче изборът не беше точно такъв – споменавайки как ще ѝ обясни причините за изгонването си в хотела, той вече беше предпоставил, че тя ще го последва.

Впоследствие стана ясно, че двамата продължават да са заедно и извън „рая“. Може би ергенката щеше да последва изгонения и ако имаше възможност да вземе решение самостоятелно, далеч от присъствието му. Няма как да знаем това. Продукцията обаче не ѝ помогна, а bTV допълнително легитимира тази основана на контрол и ограничения връзка.

Друг ерген пък забрани на половинката си да разговаря с ергенка, която я е обидила – с претенцията, че така всъщност я защитава. И дори ѝ постави условие: ако си позволи да общува с нея, той си тръгва. 

Но какво ли се учудваме – борбата с домашното насилие не е приоритет и на държавата. Важното е да се борим с „джендъра“ и да не допускаме хората в еднополови връзки до и без това не особено ефективно работещата система на защита.

В „рая“ не липсваше и сексуално насилие.

Някои ергени толкова искаха от половинките си да им „пуснат“, че понякога си позволяваха да ги понатиснат в леглото. Те се цупеха, че не постигат своето, и обвиняваха ергенките в липса на взаимност. Не вдяваха, че „не“-то, дори изречено през смях, си е „не“. Един участник беше особено настоятелен не само в леглото. Опита се да бръкне между краката на изгората си дори в двора. Не успя само защото тя е бивша спортистка и има здрави мускули.

На повечето ергенски мераци Продукцията не реагира, но след последния от описаните случаи попита ергенката дали да се намеси. Не го направи, защото участничката каза, че няма нужда. Така както институциите си измиват с ръцете с това, че много от пострадалите не си търсят правата.

Привидност и реалност

Както в политиката, така и в „рая“ не трябва да приемаме всичко за чиста монета. Не само защото нещата, които виждаме, са „за пред хората“ и поведението на участниците поне отчасти се дължи на факта, че играят роли, а и защото биваме сугестирани кое как да възприемаме.

Един от начините да се влияе на преценката ни е да се манипулира усещането ни за време. ГЕРБ, които са на власт с кратки прекъсвания от 2009 г., стоварват отговорността за всички беди върху периода между 2021 и 2024 г., когато не са участвали в правителството (макар че правителството на Николай Денков беше и тяхно).

В „рая“ времето е разтегливо дори повече, отколкото в главата на Бойко Борисов.

В началото на шоуто церемониите с розите се излъчваха веднъж седмично – в петък. Един период между две церемонии обаче се проточи цели три седмици. Така се създаде впечатлението, че участниците са прекарали много повече време заедно, отколкото реално са, и че някои драми са се разразявали в продължение на близо месец, а не по-малко от седмица.

Случваше се едно и също събитие да се излъчва в няколко поредни епизода, особено ако включва скандал. Други случки бяха показани мимоходом, а много така и не са стигнали до зрителите, понеже няма как да се излъчи всичко. Не по-маловажна обаче е

привидността в ергенските отношения,

въпреки че в някои случаи е трудно да се сложи рязка граница между привидност и реалност. Ергени и ергенки може да смятат, че обиждат, тормозят и унижават, за да става шоу, но обидите, тормозът и униженията са си истински. С любовта нещата стоят по-скоро по обратния начин. От екрана се леят огромни количества от нея, но такива са правилата на играта.

До финала стигнаха седем двойки и една тройка, като ергените (в случая с тройката – избраният от дамата ерген) трябваше да дадат на избраниците си или роза (еквивалент на „една студена вода“), или годежен пръстен. Рози получиха само две участнички, а пръстени – пет. Така че шоуто завърши с четири годежа и един полугодеж (тъй като пръстенът беше сложен на дясната ръка на ергенката от тройката със заръка да го премести на лявата, когато се почувства готова).

Годежът е обещание за съвместно бъдеще, но колко от двойките, дали си драматични любовни обещания, са заедно след края на предаването? Има данни само за една – двамата от бившата тройка, завършили с полугодеж. Именно техните отношения бяха поставяни под въпрос от другите участници по време на почти цялото шоу. Защо тя е избрала него, а не друг; защо не си намери по-подходящ и по-мъжествен; защо е „лека жена“, „волна пеперуда“, скача „от цвят на цвят“ и не може да избере? Защо той не е достатъчно „мъжествен“; гей ли е; защо ѝ дава свобода?

Злите езици говорят, че далеч от камерите се е оформила истинска тройка, а не за шоуто, точно между най-големите морализатори, упрекващи оцелялата двойка, но засега не разполагам с достатъчно данни, за да потвърдя това.

В заключение, ако човек има желание и нерви да си причинява риалити формати, те могат да ни промиват мозъците (което и основно правят), но пък и ние можем да ги използваме, за да се упражняваме да не вярваме на очите си и да развиваме критичното си мислене. Да се замисляме какво ни внушават да мразим и от кое да се разчувстваме, да имаме едно наум кой дава празни обещания и кой е превърнат в изкупителна жертва. За да не стане така, че отново да се доверим на поредните популисти.

Security updates for Thursday

Post Syndicated from jzb original https://lwn.net/Articles/1050117/

Security updates have been issued by Debian (ffmpeg, firefox-esr, libsndfile, and rear), Fedora (httpd, perl-CGI-Simple, and tinyproxy), Oracle (firefox, kernel, libsoup, mysql8.4, tigervnc, tomcat, tomcat9, and uek-kernel), SUSE (alloy, curl, dovecot24, fontforge, glib2, himmelblau, java-17-openjdk, java-21-openjdk, kernel, krb5, lasso, libvirt, mozjs128, mysql-connector-java, nvidia-open-driver-G07-signed-check, openssh, poppler, postgresql17, postgresql18, python-cbor2, python-Django, python310, python311-Django, runc, strongswan, tomcat11, and xwayland), and Ubuntu (binutils, libpng1.6, linux, linux-aws, linux-aws-5.4, linux-gcp, linux-gcp-5.4, linux-hwe-5.4,
linux-ibm, linux-ibm-5.4, linux-kvm, linux-oracle, linux-xilinx-zynqmp, linux, linux-aws, linux-aws-6.14, linux-gcp, linux-hwe-6.14, linux-raspi, linux, linux-aws, linux-gcp, linux-realtime, and qtbase-opensource-src).

The collective thoughts of the interwebz