[$] Kernel API specification and validation

Post Syndicated from corbet original https://lwn.net/Articles/1027811/

The kernel project makes a strong promise to its users: the kernel ABI will
not be changed in ways that break user-space code. The occasional failure
notwithstanding, kernel developers do try to live up to that promise. They
are handicapped by one little problem, though: there is no description of
what the kernel ABI is, and no comprehensive way to test whether a given
change breaks it. The kernel API
specification framework
proposed (in its second revision) by Sasha
Levin addresses some of those concerns, but the solution is incomplete and
does not come for free.

Build conversational AI search with Amazon OpenSearch Service

Post Syndicated from Bharav Patel original https://aws.amazon.com/blogs/big-data/build-conversational-ai-search-with-amazon-opensearch-service/

Retrieval Augmented Generation (RAG) is a well-known approach to creating generative AI applications. RAG combines large language models (LLMs) with external world knowledge retrieval and is increasingly popular for adding accuracy and personalization to AI. It retrieves relevant information from external sources, augments the input with this data, and generates responses based on both. This approach reduces hallucinations, improves fact accuracy, and allows for up-to-date, efficient, and explainable AI systems. RAG’s ability to break through classical language model limitations has made it applicable to broad AI use cases.

Amazon OpenSearch Service is a versatile search and analytics tool. It is capable of performing security analytics, searching data, analyzing logs, and many other tasks. It can also work with vector data with a k-nearest neighbors (k-NN) plugin, which makes it helpful for more complex search strategies. Because of this feature, OpenSearch Service can serve as a knowledge base for generative AI applications that integrate language generation with search results.

By preserving context over several exchanges, honing responses, and providing a more seamless user experience, conversational search enhances RAG. It helps with complex information needs, resolves ambiguities, and manages multi-turn reasoning. Conversational search provides a more natural and personalized interaction, yielding more accurate and pertinent results, even though standard RAG performs well for single queries.

In this post, we explore conversational search, its architecture, and various ways to implement it.

Solution overview

Let’s walk through the solution to build conversational search. The following diagram illustrates the solution architecture.

The new OpenSearch feature known as agents and tools is used to create conversational search. To develop sophisticated AI applications, agents coordinate a variety of machine learning (ML) tasks. Every agent has a number of tools; each intended for a particular function. To use agents and tools, you need OpenSearch version 2.13 or later.

Prerequisites

To implement this solution, you need an AWS account. If you don’t have one, you can create an account. You also need an OpenSearch Service domain with OpenSearch version 2.13 or later. You can use an existing domain or create a new domain.

To use the Amazon Titan Text Embedding and Anthropic Claude V1 models in Amazon Bedrock, you need to enable access to these foundation models (FMs). For instructions, refer to Add or remove access to Amazon Bedrock foundation models.

Configure IAM permissions

Complete the following steps to set up an AWS Identity and Access Management (IAM) role and user with appropriate permissions:

  1. Create an IAM role with the following policy that will allow the OpenSearch Service domain to invoke the Amazon Bedrock API:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "Statement1",
                "Effect": "Allow",
                "Action": [
                    "bedrock:InvokeAgent",
                    "bedrock:InvokeModel"
                ],
                "Resource": [
                    "arn:aws:bedrock:${Region}::foundation-model/amazon.titan-embed-text-v1",
                    "arn:aws:bedrock: ${Region}::foundation-model/anthropic.claude-instant-v1"
                ]
            }
        ]
    }
    

Depending on the AWS Region and model you use, specify those in the Resource section.

  1. Add opensearchservice.amazonaws.com as a trusted entity.
  2. Make a note of the IAM role Amazon Resource name (ARN).
  3. Assign the preceding policy to the IAM user that will create a connector.
  4. Create a passRole policy and assign it to IAM user that will create the connector using Python:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": "iam:PassRole",
                "Resource": "arn:aws:iam::${AccountId}:role/OpenSearchBedrock"
            }
        ]
    }
  5. Map the IAM role you created to the OpenSearch Service domain role using the following steps:
    • Log in to the OpenSearch Dashboard and open the Security page from the navigation menu.
    • Choose Roles and select ml_all_access.
    • Choose Mapped Users and Manage Mapping.
    • Under Users, add the ARN of the IAM user you created.

Establish a connection to the Amazon Bedrock model using the MLCommons plugin

In order to identify patterns and relationships, an embedding model transforms input data—such as words or images—into numerical vectors in a continuous space. Similar objects are grouped together to make it easier for AI systems to comprehend and respond to intricate user enquiries.

Semantic search concentrates on the purpose and meaning of a query. OpenSearch stores data in a vector index for retrieval and transforms it into dense vectors (lists of numbers) using text embedding models. We are using amazon.titan-embed-text-v1 hosted on Amazon Bedrock, but you will need to evaluate and choose the right model for your use case. The amazon.titan-embed-text-v1 model maps sentences and paragraphs to a 1,536-dimensional dense vector space and is optimized for the task of semantic search.

Complete the following steps to establish a connection to the Amazon Bedrock model using the MLCommons plugin:

  1. Establish a connection by using the Python client with the connection blueprint.
  2. Modify the values of the host and region parameters in the provided code block. For this example, we’re running the program in Visual Studio Code with Python version 3.9.6, but newer versions should also work.
  3. For the role ARN, use the ARN you created earlier, and run the following script using the credentials of the IAM user you created:
    import boto3
    import requests 
    from requests_aws4auth import AWS4Auth
    
    host = 'https://search-test.us-east-1.es.amazonaws.com/'
    region = 'us-east-1'
    service = 'es'
    credentials = boto3.Session().get_credentials()
    awsauth = AWS4Auth(credentials.access_key, credentials.secret_key, region, service, session_token=credentials.token)
    
    path = '_plugins/_ml/connectors/_create'
    url = host + path
    
    payload = {
      "name": "Amazon Bedrock Connector: embedding",
      "description": "The connector to bedrock Titan embedding model",
      "version": 1,
      "protocol": "aws_sigv4",
      "parameters": {
        "region": "us-east-1",
        "service_name": "bedrock",
        "model": "amazon.titan-embed-text-v1"
      },
      "credential": {
        "roleArn": "arn:aws:iam::<accountID>:role/opensearch_bedrock_external"
      },
      "actions": [
        {
          "action_type": "predict",
          "method": "POST",
          "url": "https://bedrock-runtime.${parameters.region}.amazonaws.com/model/${parameters.model}/invoke",
          "headers": {
            "content-type": "application/json",
            "x-amz-content-sha256": "required"
          },
          "request_body": "{ \"inputText\": \"${parameters.inputText}\" }",
          "pre_process_function": "connector.pre_process.bedrock.embedding",
          "post_process_function": "connector.post_process.bedrock.embedding"
        }
      ]
    }
    
    headers = {"Content-Type": "application/json"}
    
    r = requests.post(url, auth=awsauth, json=payload, headers=headers, timeout=15)
    print(r.status_code)
    print(r.text)
    
  4. Run the Python program. This will return connector_id.
    python3 connect_bedrocktitanembedding.py
    200
    {"connector_id":"nbBe65EByVCe3QrFhrQ2"}
  5. Create a model group against which this model will be registered in the OpenSearch Service domain:
    POST /_plugins/_ml/model_groups/_register
    {
      "name": "embedding_model_group",
      "description": "A model group for bedrock embedding models"
    }

    You get the following output:

    {
      "model_group_id": "1rBv65EByVCe3QrFXL6O",
      "status": "CREATED"
    }
  6. Register a model using connector_id and model_group_id:
    POST /_plugins/_ml/models/_register
    {
        "name": "titan_text_embedding_bedrock",
        "function_name": "remote",
        "model_group_id": "1rBv65EByVCe3QrFXL6O",
        "description": "test model",
        "connector_id": "nbBe65EByVCe3QrFhrQ2",
       "interface": {}
    }

You get the following output:

{
  "task_id": "2LB265EByVCe3QrFAb6R",
  "status": "CREATED",
  "model_id": "2bB265EByVCe3QrFAb60"
}
  1. Deploy a model using the model ID:
POST /_plugins/_ml/models/2bB265EByVCe3QrFAb60/_deploy

You get the following output:

{
  "task_id": "bLB665EByVCe3QrF-slA",
  "task_type": "DEPLOY_MODEL",
  "status": "COMPLETED"
}

Now the model is deployed, and you will see that in OpenSearch Dashboards on the OpenSearch Plugins page.

Create an ingestion pipeline for data indexing

Use the following code to create an ingestion pipeline for data indexing. The pipeline will establish a connection to the embedding model, retrieve the embedding, and then store it in the index.

PUT /_ingest/pipeline/cricket_data_pipeline {
    "description": "batting score summary embedding pipeline",
    "processors": [
        {
            "text_embedding": {
                "model_id": "GQOsUJEByVCe3QrFfUNq",
                "field_map": {
                    "cricket_score": "cricket_score_embedding"
                }
            }
        }
    ]
}

Create an index for storing data

Create an index for storing data (for this example, the cricket achievements of batsmen). This index stores raw text and embeddings of the summary text with 1,536 dimensions and uses the ingest pipeline we created in the previous step.

PUT cricket_data {
    "mappings": {
        "properties": {
            "cricket_score": {
                "type": "text"
            },
            "cricket_score_embedding": {
                "type": "knn_vector",
                "dimension": 1536,
                "space_type": "l2",
                "method": {
                    "name": "hnsw",
                    "engine": "faiss"
                }
            }
        }
    },
    "settings": {
        "index": {
            "knn": "true"
        }
    }
}

Ingest sample data

Use the following code to ingest the sample data for four batsmen:

POST _bulk?pipeline=cricket_data_pipeline
{"index": {"_index": "cricket_data"}}
{"cricket_score": "Sachin Tendulkar, often hailed as the 'God of Cricket,' amassed an extraordinary batting record throughout his 24-year international career. In Test cricket, he played 200 matches, scoring a staggering 15,921 runs at an average of 53.78, including 51 centuries and 68 half-centuries, with a highest score of 248 not out. His One Day International (ODI) career was equally impressive, spanning 463 matches where he scored 18,426 runs at an average of 44.83, notching up 49 centuries and 96 half-centuries, with a top score of 200 not out – the first double century in ODI history. Although he played just one T20 International, scoring 10 runs, his overall batting statistics across formats solidified his status as one of cricket's all-time greats, setting numerous records that stand to this day."}
{"index": {"_index": "cricket_data"}}
{"cricket_score": "Virat Kohli, widely regarded as one of the finest batsmen of his generation, has amassed impressive statistics across all formats of international cricket. As of April 2024, in Test cricket, he has scored over 8,000 runs with an average exceeding 50, including numerous centuries. His One Day International (ODI) record is particularly stellar, with more than 12,000 runs at an average well above 50, featuring over 40 centuries. In T20 Internationals, Kohli has maintained a high average and scored over 3,000 runs. Known for his exceptional ability to chase down targets in limited-overs cricket, Kohli has consistently ranked among the top batsmen in ICC rankings and has broken several batting records throughout his career, cementing his status as a modern cricket legend."}
{"index": {"_index": "cricket_data"}}
{"cricket_score": "Adam Gilchrist, the legendary Australian wicketkeeper-batsman, had an exceptional batting record across formats during his international career from 1996 to 2008. In Test cricket, Gilchrist scored 5,570 runs in 96 matches at an impressive average of 47.60, including 17 centuries and 26 half-centuries, with a highest score of 204 not out. His One Day International (ODI) record was equally remarkable, amassing 9,619 runs in 287 matches at an average of 35.89, with 16 centuries and 55 half-centuries, and a top score of 172. Gilchrist's aggressive batting style and ability to change the course of a game quickly made him one of the most feared batsmen of his era. Although his T20 International career was brief, his overall batting statistics, combined with his wicketkeeping skills, established him as one of cricket's greatest wicketkeeper-batsmen."}
{"index": {"_index": "cricket_data"}}
{"cricket_score": "Brian Lara, the legendary West Indian batsman, had an extraordinary batting record in international cricket during his career from 1990 to 2007. In Test cricket, Lara amassed 11,953 runs in 131 matches at an impressive average of 52.88, including 34 centuries and 48 half-centuries. He holds the record for the highest individual score in a Test innings with 400 not out, as well as the highest first-class score of 501 not out. In One Day Internationals (ODIs), Lara scored 10,405 runs in 299 matches at an average of 40.48, with 19 centuries and 63 half-centuries. His highest ODI score was 169. Known for his elegant batting style and ability to play long innings, Lara's exceptional performances, particularly in Test cricket, cemented his status as one of the greatest batsmen in the history of the game."}

Deploy the LLM for response generation

Use the following code to deploy the LLM for response generation. Modify the values of host, region, and roleArn in the provided code block.

  1. Create a connector by running the following Python program. Run the script using the credentials of the IAM user created earlier.
    import boto3
    import requests 
    from requests_aws4auth import AWS4Auth
    
    host = 'https://search-test.us-east-1.es.amazonaws.com/'
    region = 'us-east-1'
    service = 'es'
    credentials = boto3.Session().get_credentials()
    awsauth = AWS4Auth(credentials.access_key, credentials.secret_key, region, service, session_token=credentials.token)
    
    path = '_plugins/_ml/connectors/_create'
    url = host + path
    
    payload = {
      "name": "BedRock Claude instant-v1 Connector ",
      "description": "The connector to BedRock service for claude model",
      "version": 1,
      "protocol": "aws_sigv4",
      "parameters": {
        "region": "us-east-1",
        "service_name": "bedrock",
        "anthropic_version": "bedrock-2023-05-31",
        "max_tokens_to_sample": 8000,
        "temperature": 0.0001,
        "response_filter": "$.completion"
      },
       "credential": {
            "roleArn": "arn:aws:iam::accountId:role/opensearch_bedrock_external"
        },
      "actions": [
        {
          "action_type": "predict",
          "method": "POST",
          "url": "https://bedrock-runtime.${parameters.region}.amazonaws.com/model/anthropic.claude-instant-v1/invoke",
          "headers": {
            "content-type": "application/json",
            "x-amz-content-sha256": "required"
          },
          "request_body": "{\"prompt\":\"${parameters.prompt}\", \"max_tokens_to_sample\":${parameters.max_tokens_to_sample}, \"temperature\":${parameters.temperature},  \"anthropic_version\":\"${parameters.anthropic_version}\" }"
        }
      ]
     }
        
    
    headers = {"Content-Type": "application/json"}
    
    r = requests.post(url, auth=awsauth, json=payload, headers=headers, timeout=15)
    print(r.status_code)
    print(r.text)

If it ran successfully, it would return connector_id and a 200-response code:

200
{"connector_id":"LhLSZ5MBLD0avmh1El6Q"}
  1. Create a model group for this model:
    POST /_plugins/_ml/model_groups/_register
    {
        "name": "claude_model_group",
        "description": "This is an example description"
    }

This will return model_group_id; make a note of it:

{
  "model_group_id": "LxLTZ5MBLD0avmh1wV4L",
  "status": "CREATED"
}
  1. Register a model using connection_id and model_group_id:
    POST /_plugins/_ml/models/_register
    {
        "name": "anthropic.claude-v1",
        "function_name": "remote",
        "model_group_id": "LxLTZ5MBLD0avmh1wV4L",
        "description": "LLM model",
        "connector_id": "LhLSZ5MBLD0avmh1El6Q",
        "interface": {}
    }
    

It will return model_id and task_id:

{
  "task_id": "YvbVZ5MBtVAPFbeA7ou7",
  "status": "CREATED",
  "model_id": "Y_bVZ5MBtVAPFbeA7ovb"
}
  1. Finally, deploy the model using an API:
POST /_plugins/_ml/models/Y_bVZ5MBtVAPFbeA7ovb/_deploy

The status will show as COMPLETED. That means the model is successfully deployed.

{
  "task_id": "efbvZ5MBtVAPFbeA7otB",
  "task_type": "DEPLOY_MODEL",
  "status": "COMPLETED"
}

Create an agent in OpenSearch Service

An agent orchestrates and runs ML models and tools. A tool performs a set of specific tasks. For this post, we use the following tools:

  • VectorDBTool – The agent use this tool to retrieve OpenSearch documents relevant to the user question
  • MLModelTool – This tool generates user responses based on prompts and OpenSearch documents

Use the embedding model_id in VectorDBTool and LLM model_id in MLModelTool:

POST /_plugins/_ml/agents/_register {
    "name": "cricket score data analysis agent",
    "type": "conversational_flow",
    "description": "This is a demo agent for cricket data analysis",
    "app_type": "rag",
    "memory": {
        "type": "conversation_index"
    },
    "tools": [
        {
            "type": "VectorDBTool",
            "name": "cricket_knowledge_base",
            "parameters": {
                "model_id": "2bB265EByVCe3QrFAb60",
                "index": "cricket_data",
                "embedding_field": "cricket_score_embedding",
                "source_field": [
                    "cricket_score"
                ],
                "input": "${parameters.question}"
            }
        },
        {
            "type": "MLModelTool",
            "name": "bedrock_claude_model",
            "description": "A general tool to answer any question",
            "parameters": {
                "model_id": "gbcfIpEByVCe3QrFClUp",
                "prompt": "\n\nHuman:You are a professional data analysist. You will always answer question based on the given context first. If the answer is not directly shown in the context, you will analyze the data and find the answer. If you don't know the answer, just say don't know. \n\nContext:\n${parameters.cricket_knowledge_base.output:-}\n\n${parameters.chat_history:-}\n\nHuman:${parameters.question}\n\nAssistant:"
            }
        }
    ]
}

This returns an agent ID; take note of the agent ID, which will be used in subsequent APIs.

Query the index

We have batting scores of four batsmen in the index. For the first query, let’s specify the player name:

POST /_plugins/_ml/agents/<agent ID>/_execute {
    "parameters": {
        "question": "What is batting score of Sachin Tendulkar ?"
    }
}

Based on context and available information, it returns the batting score of Sachin Tendulkar. Note the memory_id from the response; you will need it for subsequent questions in the next steps.

We can ask a follow-up question. This time, we don’t specify the player name and expect it to answer based on the earlier question:

POST /_plugins/_ml/agents/<agent ID>/_execute {
    "parameters": {
        "question": " How many T20 international match did he play?",
        "next_action": "then compare with Virat Kohlis score",
        "memory_id": "so-vAJMByVCe3QrFYO7j",
        "message_history_limit": 5,
        "prompt": "\n\nHuman:You are a professional data analysist. You will always answer question based on the given context first. If the answer is not directly shown in the context, you will analyze the data and find the answer. If you don't know the answer, just say don't know. \n\nContext:\n${parameters.population_knowledge_base.output:-}\n\n${parameters.chat_history:-}\n\nHuman:always learn useful information from chat history\nHuman:${parameters.question}, ${parameters.next_action}\n\nAssistant:"
    }
}

In the preceding API, we use the following parameters:

  • Question and Next_action – We also pass the next action to compare Sachin’s score with Virat’s score.
  • Memory_id – This is memory assigned to this conversation. Use the same memory_id for subsequent questions.
  • Prompt – This is the prompt you give to the LLM. It includes the user’s question and the next action. The LLM should answer only using the data indexed in OpenSearch and must not invent any information. This way, you prevent hallucination.

Refer to ML Model tool for more details about setting up these parameters and the GitHub repo for blueprints for remote inferences.

The tool stores the conversation history of the questions and answers in the OpenSearch index, which is used to refine answers by asking follow-up questions.

In real-world scenarios, you can map memory_id against the user’s profile to preserve the context and isolate the user’s conversation history.

We have demonstrated how to create a conversational search application using the built-in features of OpenSearch Service.

Clean up

To avoid incurring future charges, delete the resources created while building this solution:

  1. Delete the OpenSearch Service domain.
  2. Delete the connector.
  3. Delete the index.

Conclusion

In this post, we demonstrated how to use OpenSearch agents and tools to create a RAG pipeline with conversational search. By integrating with ML models, vectorizing questions, and interacting with LLMs to improve prompts, this configuration oversees the entire process. This method allows you to quickly develop AI assistants that are ready for production without having to start from scratch.

If you’re building a RAG pipeline with conversational history to let users ask follow-up questions for more refined answers, give it a try and share your feedback or questions in the comments!


About the author

Bharav Patel is a Specialist Solution Architect, Analytics at Amazon Web Services. He primarily works on Amazon OpenSearch Service and helps customers with key concepts and design principles of running OpenSearch workloads on the cloud. Bharav likes to explore new places and try out different cuisines.

Enhance stability with dedicated cluster manager nodes using Amazon OpenSearch Service

Post Syndicated from Chinmayi Narasimhadevara original https://aws.amazon.com/blogs/big-data/enhance-stability-with-dedicated-cluster-manager-nodes-using-amazon-opensearch-service/

Amazon OpenSearch Service is a managed service that you can use to secure, deploy, and operate OpenSearch clusters at scale in the AWS Cloud. With OpenSearch Service, you can configure clusters with different types of node options such as data nodes, dedicated cluster manager nodes, dedicated coordinator nodes, and UltraWarm nodes. When configuring your OpenSearch Service domain, you can exercise different node options to manage your cluster’s overall stability, performance, and resiliency.

In this post, we show how to enhance the stability of your OpenSearch Service domain with dedicated cluster manager nodes and how using these in deployment enhances your cluster’s stability and reliability.

The benefit of dedicated cluster manager nodes

A dedicated cluster manager node handles the behind-the-scenes work of running an OpenSearch Service cluster, but it doesn’t store actual data or process search requests. In the absence of dedicated cluster manager nodes, OpenSearch Service will use data nodes for cluster management; combining these responsibilities on the data nodes can impact performance and stability because data operations (like indexing and searching) compete with critical cluster management tasks for computing resources. The dedicated cluster manager node is responsible for several key tasks: monitoring and keeping track of all the data nodes in the cluster, knowing how many indexes and shards there are and where they’re located, and routing data to the correct places. They also update and share the cluster state whenever something changes, like creating an index or adding and removing nodes. The problem, however, is that when traffic gets heavy, the cluster manager node can get overloaded and become unresponsive. If this happens, your cluster will not respond to write requests until it elects a new cluster manager, at which point the cycle might repeat itself. You can alleviate this issue by deploying dedicated cluster manager instances, whereby this separation of duties between the manager node and the data nodes results in a much more stable cluster.

Calculating the number of dedicated cluster manager nodes

In OpenSearch Service, a single node is elected as the cluster manager from all eligible nodes through a quorum-based voting process, confirming consensus before taking on the responsibility of coordinating cluster-wide operations and maintaining the cluster’s state. Quorum is the minimum number of nodes that need to agree before the cluster makes important decisions. It helps keep your data consistent and your cluster running smoothly. When you use dedicated cluster manager nodes, only those nodes are eligible for election and OpenSearch Service sets the quorum to half of the nodes, rounded down to the nearest whole number, plus one. One dedicated cluster manager node is explicitly prohibited by OpenSearch Service because you have no backup in the event of a failure. Using three dedicated cluster manager nodes makes sure that even if one node fails, the remaining two can still reach a quorum and maintain cluster operations. We recommend three dedicated cluster manager nodes for production use cases. Multi-AZ with standby is an OpenSearch Service feature designed to deliver four 9s of availability using a third AWS Availability Zone as a standby. When you use Multi-AZ with standby, the service requires three dedicated cluster manager nodes. If you deploy with Multi-AZ without standby or Single-AZ, we still recommend three dedicated cluster manager nodes. It provides two backup nodes in the event of one cluster manager node failure and the necessary quorum (two) to elect a new manager. You can choose three or five dedicated cluster manager nodes.

Having five dedicated cluster manager nodes works as well as three, and you can lose two nodes while maintaining a quorum. But because only one dedicated cluster manager node is active at any given time, this configuration means you pay for four idle nodes.

Cluster manager node configurations for different domain creation methods

This section explains the resources each domain creation method and template deploy when you set up an OpenSearch Service domain.

With the Easy create option, you can quickly create a domain using ‘multi-AZ with standby’ for high availability three-cluster manager nodes distributed across three Availability Zones. The following table summarizes the configuration.

Domain Creation Method Output
Easy Create

Dedicated cluster manager node: Yes

Number of cluster manager nodes: 3

Availability Zones: 3

Standby: Yes

The Standard create option provides templates for ‘Production’ and ‘Dev/test’workloads. Both templates come with a Domain with standby and a Domain without standby deployment choice. The following table summarizes these configuration options.

Domain Creation Method Template Deployment Option Output
Standard Create Production Domain with standby

Requires dedicated cluster manager node

Number of cluster manager nodes: 3

Availability Zones: 3

Standby: Yes

Instance type choice: Yes

Standard create Production Domain without standby

Requires dedicated cluster manager node

Number of cluster manager nodes: 3, 5

Availability Zones: 3

Standby: No

Instance type choice: Yes

Standard Create Dev/test Domain with standby

Requires dedicated cluster manager node

Number of cluster manager nodes: 3

Availability Zones: 3

Standby: Yes

Instance type choice: Yes

Standard create Dev/test Domain without standby Does not require dedicated cluster manager node

Choosing a dedicated cluster manager instance type

Dedicated cluster manager instances typically handle critical cluster operations like shard distribution and index management and track cluster state changes. It’s recommended to select a comparatively smaller instance type. Refer to Choosing instance types for dedicated master nodes for more information on instance types for dedicated cluster manager nodes.

You should expect to occasionally adjust cluster manager instance size and type as your workload evolves over time. As with all scale questions, you need to monitor performance and make sure you have enough CPU and Java virtual machine (JVM) heap for your dedicated cluster managers. We recommend using Amazon CloudWatch alarms to monitor the following CloudWatch metrics, and adjust according to the alarm state:

  • ManagerCPUUtilization – Maximum is greater than or equal to 50% for 15 minutes, three consecutive times
  • ManagerJVMMemoryPressure – Maximum is greater than or equal to 95% for 1 minute, three consecutive times

Conclusion

Dedicated cluster manager nodes provide added stability and protection against split-brain situations, can be of a different instance type than data nodes, and are an obvious benefit when OpenSearch Service is backing mission-critical applications for production workloads. They are typically not required for development workloads like proof of concept because the cost of running a dedicated cluster manager node exceeds the tangible benefits of keeping the cluster up and running. To learn more about OpenSearch best practices, see link.


About the authors

Imtiaz (Taz) Sayed is the WW Tech Leader for Analytics at AWS. He enjoys engaging with the community on all things data and analytics. He can be reached through LinkedIn.

Chinmayi Narasimhadevara is a Senior Solutions Architect focused on Data Analytics and AI at AWS. She helps customers build advanced, highly scalable, and performant solutions.

Security updates for Thursday

Post Syndicated from jake original https://lwn.net/Articles/1028554/

Security updates have been issued by AlmaLinux (.NET 9.0, aardvark-dns, apache-commons-beanutils, bootc, buildah, corosync, delve and golang, exiv2, expat, firefox, ghostscript, git, git-lfs, gnutls, grafana, grafana-pcp, grub2, gstreamer1, gstreamer1-plugins-bad-free, gstreamer1-plugins-ugly-free, and gstreamer1-rtsp-server, gstreamer1-plugins-base, gstreamer1-plugins-good, gvisor-tap-vsock, iptraf-ng, java-21-openjdk, kernel, keylime-agent-rust, krb5, libarchive, libblockdev, libsoup3, libtasn1, libvpx, libxslt, microcode_ctl, mod_auth_openidc, nodejs22, nodejs:20, openjpeg2, osbuild and osbuild-composer, perl-FCGI, perl-Module-ScanDeps, perl-YAML-LibYAML, php, php:8.2, php:8.3, podman, protobuf, python-jinja2, python-requests, python3.11, python3.12, python3.12-cryptography, python3.9, rpm-ostree, rsync, rust-bootupd, skopeo, thunderbird, tigervnc, tomcat, tomcat9, webkit2gtk3, xdg-utils, xorg-x11-server, and xorg-x11-server-Xwayland), Debian (ring), Mageia (libarchive and rootcerts, nss & firefox), Oracle (.NET 9.0, corosync, firefox, osbuild-composer, pam, python3, python3.11, python3.12, python3.9, skopeo, sudo, and thunderbird), Red Hat (microcode_ctl, pam, php, thunderbird, tigervnc, xorg-x11-server, xorg-x11-server and xorg-x11-server-Xwayland, and xorg-x11-server-Xwayland), SUSE (clamav, icu, libgepub, libsoup, python-requests, tomcat, and xorg-x11-server), and Ubuntu (clamav, logback, mongo-c-driver, pcs, and python-flask-cors).

Kaltura reduces observability operational costs by 60% with Amazon OpenSearch Service

Post Syndicated from Ido Ziv original https://aws.amazon.com/blogs/big-data/kaltura-reduces-observability-operational-costs-by-60-with-amazon-opensearch-service/

This post is co-written with Ido Ziv from Kaltura.

As organizations grow, managing observability across multiple teams and applications becomes increasingly complex. Logs, metrics, and traces generate vast amounts of data, making it challenging to maintain performance, reliability, and cost-efficiency.

At Kaltura, an AI-infused video-first company serving millions of users across hundreds of applications, observability is mission-critical. Understanding system behavior at scale isn’t just about troubleshooting—it’s about providing seamless experiences for customers and employees alike. But achieving effective observability at this scale comes with challenges: managing spans; correlating logs, traces, and events across distributed systems; and maintaining visibility without overwhelming teams with noise. Balancing granularity, cost, and actionable insights requires constant tuning and thoughtful architecture.

In this post, we share how Kaltura transformed its observability strategy and technological stack by migrating from a software as a service (SaaS) logging solution to Amazon OpenSearch Service—achieving higher log retention, a 60% reduction in cost, and a centralized platform that empowers multiple teams with real-time insights.

Observability challenges at scale

Kaltura ingests over 8TB of logs and traces daily, processing more than 20 billion events across 6 production AWS Regions and over 200 applications—with log spikes reaching up to 6 GB per second. This immense data volume, combined with a highly distributed architecture, created significant challenges in observability. Historically, Kaltura relied on a SaaS-based observability solution that met initial requirements but became increasingly difficult to scale. As the platform evolved, teams generated disparate log formats, applied retention policies that no longer reflected data value, and operated more than 10 organically grown observability sources. The lack of standardization and visibility required extensive manual effort to correlate data, maintain pipelines, and troubleshoot issues – leading to rising operational complexity and fixed costs that didn’t scale efficiently with usage.

Kaltura’s DevOps team recognized the need to reassess their observability solution and began exploring a variety of options, from self-managed platforms to fully managed SaaS offerings. After a comprehensive evaluation, they made the strategic decision to migrate to OpenSearch Service, using its advanced features such as Amazon OpenSearch Ingestion, the Observability plugin, UltraWarm storage, and Index State Management.

Solution overview

Kaltura created a new AWS account that would be a dedicated observability account, where OpenSearch Service was deployed. Logs and traces were collected from different accounts and producers such as microservices on Amazon Elastic Kubernetes Service (Amazon EKS) and services running on Amazon Elastic Compute Cloud (Amazon EC2).

By using AWS services such as AWS Identity and Access Management (IAM), AWS Key Management Service (AWS KMS), and Amazon CloudWatch, Kaltura was able to meet the standards to create a production-grade system while keeping security and reliability in mind. The following figure shows a high-level design of the environment setup.

Ingestion

As seen in the following diagram, logs are shipped using log shippers, also known as collectors. In Kaltura’s case, they used Fluent Bit. A log shipper is a tool designed to collect, process, and transport log data from various sources to a centralized location, such as log analytics platforms, management systems, or an aggregator system. Fluent Bit was used in all sources and also provided light processing abilities. Fluent Bit was deployed as a daemonset in Kubernetes. The application development teams didn’t change their code, because the Fluent Bit pods were reading the stdout of the application pods.

The following code is an example of FluentBit configurations for Amazon EKS:

[INPUT]
   Name                tail
   Path                /var/log/containers/*.log
   Tag                 kube.*
   Skip_Long_Lines     On
   multiline.parser    docker, cri
[FILTER]
   alias               k8s
   # kubernetes filter to parse all logs
   Name                kubernetes
   Match               kube.*
   Kube_Tag_Prefix     kube.var.log.containers.
   Annotations         On
   Labels              Off
   Merge_Log           On
   Keep_Log            Off
   Kube_URL            https://kubernetes.default.svc.cluster.local:443 
[FILTER]
   alias               apps
   Name                rewrite_tag
   Match               kube.*
   Rule                $kubernetes['annotations']['kaltura.com/observability'] ^apps$ 
[OUTPUT]
   Name                http
   Match               apps.*
   Alias               apps
   Host                xxxxx.us-east-1.osis.amazonaws.com
   Port                443
   URI                 /log/apps
   Format              json
   aws_auth            true
   aws_region          us-east-1
   aws_service         osis
   aws_role_arn        arn:aws:iam::xxxxx:role/osis-ingestion-role
   Log_Level           trace
   tls On

Spans and traces were collected directly from the application layer using a seamless integration approach. To facilitate this, Kaltura deployed an OpenTelemetry Collector (OTEL) using the OpenTelemetry Operator for Kubernetes. Additionally, the team developed a custom OTEL code library, which was incorporated into the application code to efficiently capture and log traces and spans, providing comprehensive observability across their system.

Data from Fluent Bit and OpenTelemetry Collector was sent to OpenSearch Ingestion, a fully managed, serverless data collector that delivers real-time log, metric, and trace data to OpenSearch Service domains and Amazon OpenSearch Serverless collections. Each producer sent data to a specific pipeline, one for logs and one for traces, where data was transformed, aggregated, enriched, and normalized before being sent to OpenSearch Service. The trace pipeline used the otel_trace and service_map processors, while using the OpenSearch Ingestion OpenTelemetry trace analytics blueprint.

The following code is an example of the OpenSearch Ingestion pipeline for logs:

version: "2"
entry-pipeline:
 source:
   http:
     path: "/log/apps"

 processor:
   - add_entries:
       entries:
       - key: "log_type"
         value: "default"
       - key: "log_type"
         value: "api"
         add_when: 'contains(/filename, "api.log")'
         overwrite_if_key_exists: true
       - key: "log_type"
         value: "stats"
         add_when: 'contains(/filename, "stats.log")'
         overwrite_if_key_exists: true
       - key: "log_type"
         value: "event"
         add_when: 'contains(/filename, "event.log")'
         overwrite_if_key_exists: true
       - key: "log_type"
         value: "login"
         add_when: 'contains(/filename, "login.log")'
         overwrite_if_key_exists: true

   - grok:
       grok_when: '/log_type == "api"'
       match:
         log: ['^\[%%{DATA:timestamp}] \[%%{DATA:logIp}\] \[%%{DATA:host}\] \[%%{WORD:id}\] %%{WORD:priorityName}\(%%{NUMBER:priority}\): \[memory: %%{DATA:memory} MB, real: %%{DATA:real}MB\] %%{GREEDYDATA:message}']

   - date:
       match:
         - key: timestamp
           patterns: ["dd-MMM-yyyy HH:mm:ss", "dd/MMM/yyyy:HH:mm:ss Z", "EEE MMM dd HH:mm:ss.SSSSSS yyyy"]

       destination: "@timestamp"
       output_format: "yyyy-MM-dd'T'HH:mm:ss"

   - rename_keys:
       entries:
       - from_key: "timestamp"
         to_key: "@timestamp"
         overwrite_if_to_key_exists: false
       - from_key: "date"
         to_key: "@timestamp"
         overwrite_if_to_key_exists: false

   - drop_events:
       drop_when: 'contains(/filename, "simplesamlphp.log")'


 sink:
   - opensearch:
       hosts: ["${opensearch_host}"]
       index: '$${/env}-api-$${/log_type}-app-logs'
       index_type: custom
       action: create
       bulk_size: 20
       aws:
         sts_role_arn: ${sts_role_arn}
         region:  ${region}
       dlq:
         s3:
           bucket: "${bucket}"
           key_path_prefix: 'my-app-dlq-files'
           region: "${region}"
           sts_role_arn: "${sts_role_arn}"

The preceding example shows the use of processors such as grok, date, add_entries, rename_keys, and drop_events:

  • add_entries:
    • Adds a new field log_type based on filename
    • Default: “default”
    • If the filename contains specific substrings (such as api.log or stats.log), it assigns a more specific type
  • grok:
    • Applies Grok parsing to logs of type “api”
    • Extracts fields like timestamp, logIp, host, priorityName, priority, memory, real, and message using a custom pattern
  • date:
    • Parses timestamp strings into a standard datetime format
    • Stores it in a field called @timestamp based on ISO8601 format
    • Handles multiple timestamp patterns
  • rename_keys:
    • timestamp or date are renamed into @timestamp
    • Does not overwrite if @timestamp already exists
  • drop_events:
    • Drops logs where filename contains simplesamlphp.log
    • This is a filtering rule to ignore noisy or irrelevant logs

The following is an example of the input of a log line:

   "log": "[25-Mar-2025 18:23:18] [127.0.0.1] [the-most-awesome-server-in-kaltura] [67e2f496cc321] INFO(6): [memory: 4.51 MB, real: 6MB] [request: 1] [time: 0.0263s / total: 0.0263s]",

After processing, we get the following code:

    "log_type": "api",
    "priorityName": "INFO",
    "memory": "4.51",
    "host": "the-most-awesome-server-in-kaltura",
    "real": "6",
    "priority": "6",
    "message": "[request: 1] [time: 0.0263s / total: 0.0263s]",
    "logIp": "127.0.0.1",
    "id": "67e2f496cc321",
    "@timestamp": "2025-03-25T18:23:18"

Kaltura followed some OpenSearch Ingestion best practices, such as:

  • Including a dead-letter queue (DLQ) in pipeline configuration. This can significantly help troubleshoot pipeline issues.
  • Starting and stopping pipelines to optimize cost-efficiency, when possible.
  • During the proof of concept stage:
    • Installing Data Prepper locally for faster development iterations.
    • Disabling persistent buffering to expedite blue-green deployments.

Achieving operational excellence with efficient log and trace management

Logs and traces play a vital role in identifying operational issues, but they come with unique challenges. First, they represent time series data, which inherently evolves over time. Second, their value typically diminishes as time passes, making efficient management crucial. Third, they are append-only in nature. With OpenSearch, Kaltura faced distinct trade-offs between cost, data retention, and latency. The goal was to make sure valuable data remained accessible to engineering teams with minimal latency, but the solution also needed to be cost-effective. Balancing these factors required thoughtful planning and optimization.

Data was ingested to OpenSearch data streams, which simplifies the process of ingesting append-only time series data. Several Index State Management (ISM) policies were applied to different data streams, which were dependent on log retention requirements. ISM policies handled moving indexes from hot storage to UltraWarm, and eventually deleting the indexes. This allowed a customizable and cost-effective solution, with low latency for querying new data and reasonable latency for querying historical data.

The following example ISM policy makes sure indexes are managed efficiently, rolled over, and moved to different storage tiers based on their age and size, and eventually deleted after 60 days. If an action fails, it is retried with an exponential backoff strategy. In case of failures, notifications are sent to relevant teams to keep them informed.

{
    "id": "retention",
    "policy": {
        "description": "production ISM",
        },
        "default_state": "hot",
        "states": [
            {
                "name": "hot",
                "actions": [
                    {
                        "retry": {
                            "count": 5,
                            "backoff": "exponential",
                            "delay": "1h"
                        },
                        "rollover": {
                            "min_primary_shard_size": "30gb",
                            "copy_alias": false
                        }
                    }
                ],
                "transitions": [
                    {
                        "state_name": "warm",
                        "conditions": {
                            "min_index_age": "2d"
                        }
                    }
                ]
            },
            {
                "name": "warm",
                "actions": [
                    {
                        "retry": {
                            "count": 5,
                            "backoff": "exponential",
                            "delay": "1h"
                        },
                        "warm_migration": {}
                    }
                ],
                "transitions": [
                    {
                        "state_name": "cold",
                        "conditions": {
                            "min_index_age": "14d"
                        }
                    }
                ]
            },
            {
                "name": "cold",
                "actions": [
                    {
                        "retry": {
                            "count": 5,
                            "backoff": "exponential",
                            "delay": "1h"
                        },
                        "cold_migration": {
                            "start_time": null,
                            "end_time": null,
                            "timestamp_field": "@timestamp",
                            "ignore": "none"
                        }
                    }
                ],
                "transitions": [
                    {
                        "state_name": "delete",
                        "conditions": {
                            "min_index_age": "60d"
                        }
                    }
                ]
            },
            {
                "name": "delete",
                "actions": [
                    {
                        "retry": {
                            "count": 3,
                            "backoff": "exponential",
                            "delay": "1m"
                        },
                        "cold_delete": {}
                    }
                ],
                "transitions": []
            }
        ],
        "ism_template": [
            {
                "index_patterns": [
                    "*-logs"
                ],
                "priority": 50,
            }
        ]
    }
}

To create a data stream in OpenSearch, a definition of index template is required, which configures how the data stream and its backing indexes will behave. In the following example, the index template specifies key index settings such as the number of shards, replication, and refresh interval—controlling how data is distributed, replicated, and refreshed across the cluster. It also defines the mappings, which describe the structure of the data—what fields exist, their types, and how they should be indexed. These mappings make sure the data stream knows how to interpret and store incoming log data efficiently. Finally, the template enables the @timestamp field as the time-based field required for a data stream.

{
  "index_patterns": [
    "*my-app-logs"
  ],
  "template": {
    "settings": {
      "index.number_of_shards": "32",
      "index.number_of_replicas": "0",
      "index.refresh_interval": "60s"
    },
    "mappings": {
      "properties": {
        "priorityName": {
          "type": "keyword"
        },
        "log_type": {
          "type": "keyword"
        },
        "@timestamp": {
          "type": "date"
        },
        "memory": {
          "type": "float"
        },
        "host": {
          "type": "keyword"
        },
        "pid": {
          "type": "keyword"
        },
        "real": {
          "type": "float"
        },
        "env": {
          "type": "keyword"
        },
        "message": {
          "type": "text"
        },
        "priority": {
          "type": "integer"
        },
        "logIp": {
          "type": "ip"
        }
      }
    }
  },
  "composed_of": [],
  "priority": "100",
  "_meta": {
    "flow": "simple"
  },
  "data_stream": {
    "timestamp_field": {
      "name": "@timestamp"
    }
  },
  "name": "my-app-logs"
}

Implementing role-based access control and user access

The new observability platform is accessed by many types of users; internal users log in to OpenSearch Dashboards using SAML-based federation with Okta. The following diagram illustrates the user flow.

Each user accesses the dashboards to view observability items relevant to their role. Fine-grained access control (FGAC) is enforced in OpenSearch using built-in IAM role and SAML group mappings to implement role-based access control (RBAC).When users log in to the OpenSearch domain, they are automatically routed to the appropriate tenant based on their assigned role. This setup makes sure developers can create dashboards tailored to debugging within development environments, and support teams can build dashboards focused on identifying and troubleshooting production issues. The SAML integration alleviates the need to manage internal OpenSearch users entirely.

For each role in Kaltura, a corresponding OpenSearch role was created with only the necessary permissions. For instance, support engineers are granted access to the monitoring plugin to create alerts based on logs, whereas QA engineers, who don’t require this functionality, are not granted that access.

The following screenshot shows the role of the DevOps engineers defined with cluster permissions.

These users are routed to their own dedicated DevOps tenant, to which they only have write access. This makes it possible for different users from different roles in Kaltura to create the dashboard items that focus on their priorities and needs. OpenSearch supports backend role mapping; Kaltura mapped the Okta group to the role so when a user logs in from Okta, they automatically get assigned based on their role.

This also works with IAM roles to facilitate automations in the cluster using external services, such as OpenSearch Ingestion pipelines, as can be seen in the following screenshot.

Using observability features and service mapping for enhanced trace and log correlation

After a user is logged in, they can use the Observability plugins, view surrounding events in logs, correlate logs and traces, and use the Trace Analytics plugin. Users can inspect traces and spans, and group traces with latency information using built-in dashboards. Users can also drill down to a specific trace or span and correlate it back to log events. The service_map processor used in OpenSearch Ingestion sends OpenTelemetry data to create a distributed service map for visualization in OpenSearch Dashboards.

Using the combined signals of traces and spans, OpenSearch discovers the application connectivity and maps them to a service map.

After OpenSearch ingests the traces and spans from Otel, they are aggregated to groups according to paths and trends. Durations are also calculated and presented to the user over time.

With a trace ID, it’s possible to filter out all the relevant spans by the service and see how long each took, identifying issues with external services such as MongoDB and Redis.

From the spans, users can discover the relevant logs.

Post-migration enhancements

After the migration, a strong developer community emerged within Kaltura that embraced the new observability solution. As adoption grew, so did requests for new features and enhancements aimed at improving the overall developer experience.

One key improvement was extending log retention. Kaltura achieved this by re-ingesting historical logs from Amazon Simple Storage Service (Amazon S3) using a dedicated OpenSearch Ingestion pipeline with Amazon S3 read permissions. With this enhancement, teams can access and analyze logs from up to a year ago using the same familiar dashboards and filters.

In addition to monitoring EKS clusters and EC2 instances, Kaltura expanded its observability stack by integrating more AWS services. Amazon API Gateway and AWS Lambda were introduced to support log ingestion from external vendors, allowing for seamless correlation with existing data and broader visibility across systems.

Finally, to empower teams and promote autonomy, data stream templates and ISM policies are managed directly by developers within their own repositories. By using infrastructure as code tools like Terraform, developers can define index mappings, alerts, and dashboards as code—versioned in Git and deployed consistently across environments.

Conclusion

Kaltura successfully implemented a smart log retention strategy, extending real time retention from 5 days for all log types to 30 days for critical logs, while maintaining cost-efficiency through the use of UltraWarm nodes. This approach led to a 60% reduction in costs compared to their previous solution. Additionally, Kaltura consolidated their observability platform, streamlining operations by merging 10 separate systems into a unified, all-in-one solution. This consolidation not only improved operational efficiency but also sparked increased engagement from developer teams, driving feature requests, fostering internal design collaborations, and attracting early adopters for new enhancements. If Kaltura’s journey has inspired you and you’re thinking about implementing a similar solution in your organization, consider these steps:


About the authors

Ido Ziv is a DevOps team leader in Kaltura with over 6 years of experience. His hobbies include sailing and Kubernetes (but not at the same time).

Roi Gamliel is a Senior Solutions Architect helping startups build on AWS. He is passionate about the OpenSearch Project, helping customers fine-tune their workloads and maximize results.

Yonatan Dolan is a Principal Analytics Specialist at Amazon Web Services. He is located in Israel and helps customers harness AWS analytical services to use data, gain insights, and derive value.

Surveillance Used by a Drug Cartel

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/07/surveillance-used-by-a-drug-cartel.html

Once you build a surveillance system, you can’t control who will use it:

A hacker working for the Sinaloa drug cartel was able to obtain an FBI official’s phone records and use Mexico City’s surveillance cameras to help track and kill the agency’s informants in 2018, according to a new US justice department report.

The incident was disclosed in a justice department inspector general’s audit of the FBI’s efforts to mitigate the effects of “ubiquitous technical surveillance,” a term used to describe the global proliferation of cameras and the thriving trade in vast stores of communications, travel, and location data.

[…]

The report said the hacker identified an FBI assistant legal attaché at the US embassy in Mexico City and was able to use the attaché’s phone number “to obtain calls made and received, as well as geolocation data.” The report said the hacker also “used Mexico City’s camera system to follow the [FBI official] through the city and identify people the [official] met with.”

FBI report.

По прайда ще ги познаете

Post Syndicated from Светла Енчева original https://www.toest.bg/po-prayda-shte-gi-poznaete/

По прайда ще ги познаете

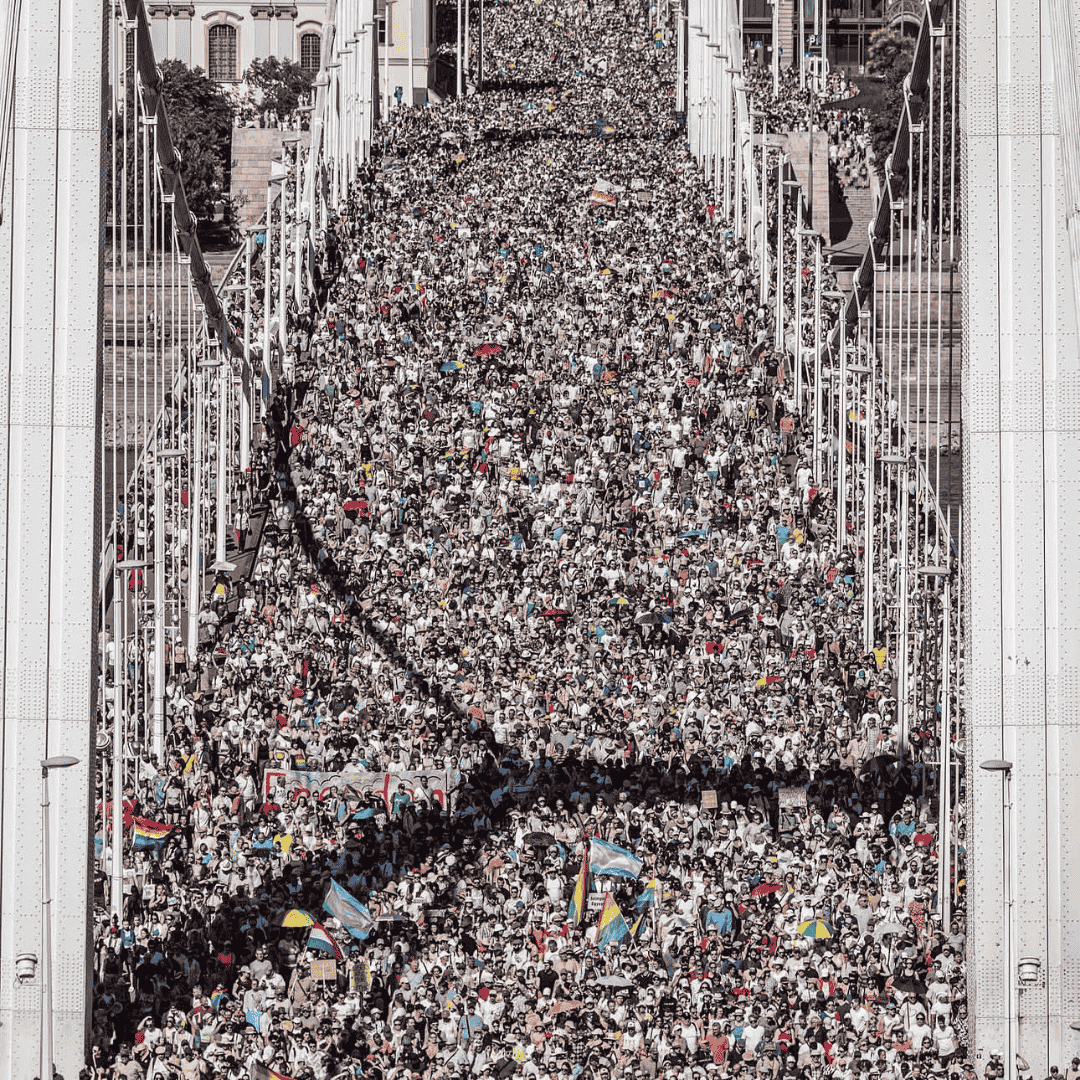
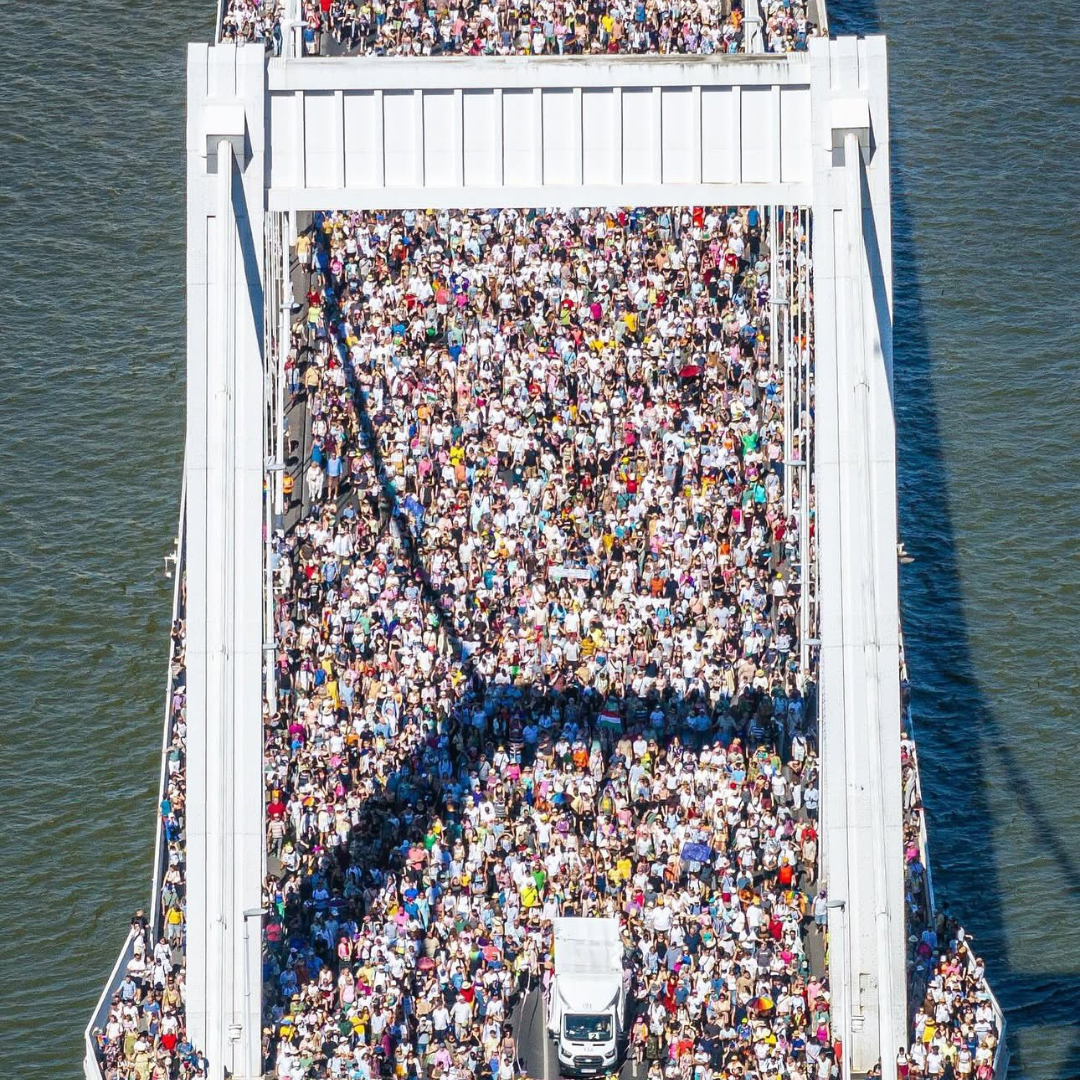
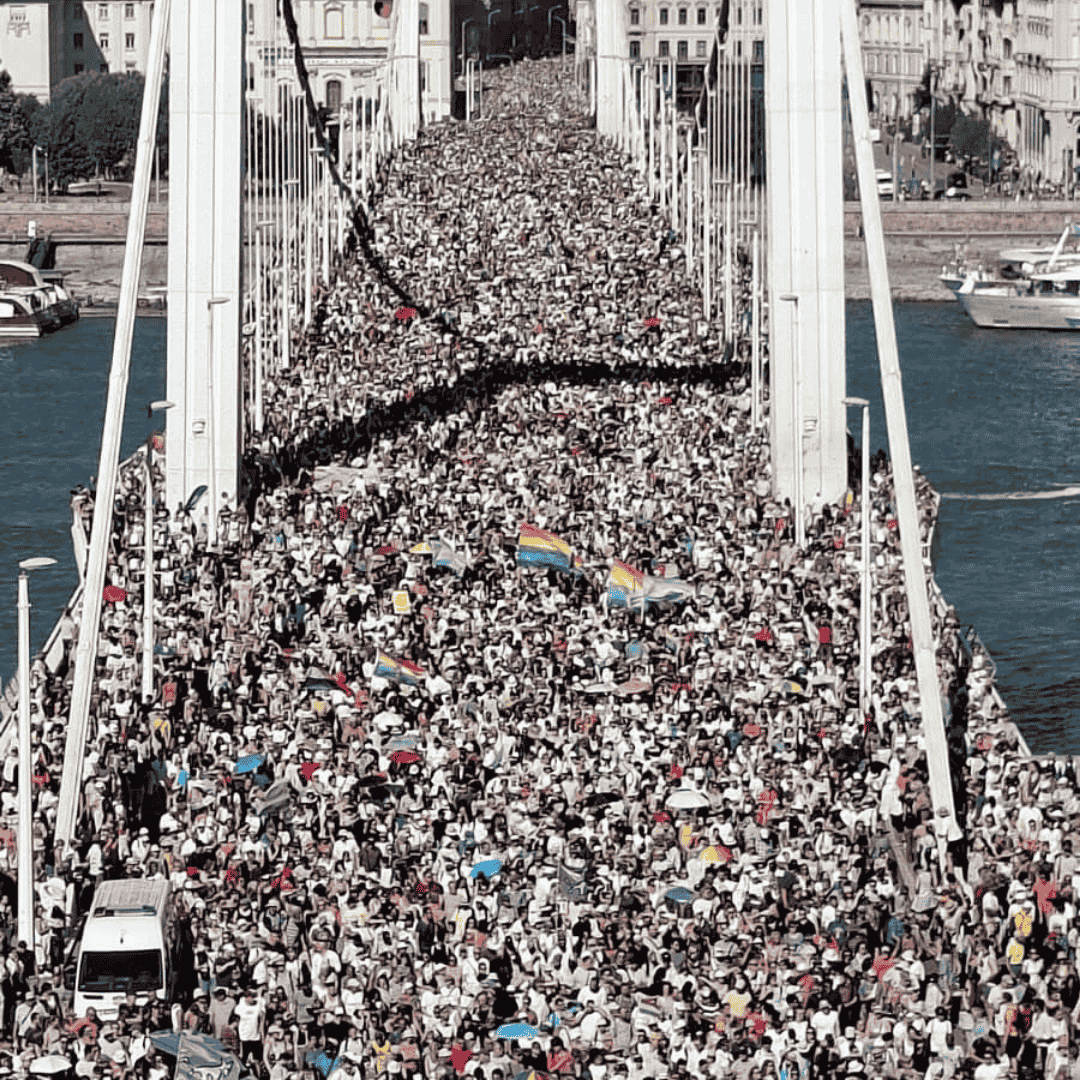
За прайдовете обикновено се говори в контекста на правата на ЛГБТИ+ хората. Тазгодишният в Будапеща обаче влезе в световните новини най-вече с друго – с мащаба си. По оценки на организаторите в него са се включили между 180 000 и 200 000 души. Това се равнява на около 5% от населението на Унгария, наброяващо 9 630 000 души (което не означава, че участниците са само унгарци – сред тях има и хора от други държави, включително България). Дори разчетите на организаторите да са раздути, снимки на събитието от въздуха създават известна представа за огромния му мащаб. Със сигурност в Будапеща не е имало по-голям прайд от този.

Забраната като катализатор

Рекордната посещаемост на прайда в Будапеща всъщност е реакция срещу забраната му. По този повод възникна и нова дума – orbanned, която може да се преведе като „орбаннат“ (от Орбан и „баннат“ – забранен). Тя означава увеличаване на популярността на нещо като ефект от забраната му.

През април 2025 г. унгарският парламент прие с огромно мнозинство поправка в конституцията на страната, чиято цел беше публичните събития, свързани с правата на ЛГБТИ+ хората, да се обявят за противоконституционни. Новият текст в основния закон е формулиран по следния начин: 

[…] правото на децата на правилно морално, физическо и умствено развитие – с изключение на правото на живот – има предимство пред всички други основни права, включително правото на събрания.

Предпоставка за тази формулировка е схващането, че със самото си присъствие ЛГБТИ+ хората са заплаха за децата – теза, широко споделяна от руската пропаганда и от ултраконсервативни кръгове, зад която не стои научна обосновка. С подобни аргументи обаче бяха постепенно ограничавани правата на сексуалните и половите малцинства в Русия, докато самото им съществуване беше обявено за „екстремизъм“. Последваха хайки в гей клубове и сауни и присъди на жени заради обичките, които носят.

Месец преди конституционната промяна Унгария забрани прайда със закон. Добавката в Основния закон на страната би следвало да бетонира законовата промяна.

И все пак защо ограничаването на една малцинствена група постигна обратния ефект?

Когато се предприемат законови и конституционни мерки против ЛГБТИ+ хората, това е само средство. Вторачването в интимността е стъпка към установяването на тотален контрол върху живота на всички, независимо от сексуалната им ориентация или половата им идентичност. Неслучайно подобни посегателства обикновено вървят заедно с опити за ограничаване не само на абортите, а и на неправителствения сектор, медиите, свободата на изразяване, политическия плурализъм.

След 15 години управление на „нелибералната демокрация“ на Виктор Орбан унгарците осъзнават по трудния начин, че забраната на прайда е поредният пирон в ковчега на либералната демокрация. Ето защо присъствието на шествието е подкрепа не толкова за куиър хората, колкото за демокрацията – такава, каквато е тя в европейските страни, които не са проядени от руска пропаганда.

Ролята на кмета

Как обаче се провежда забранено събитие? За да стане възможен прайдът в Будапеща, отговорност поема кметът на унгарската столица – опозиционният лидер Гергели Карачони. Тъй като е ясно, че полицията няма как да разреши двойно забранено (и по закон, и по конституция) шествие, Карачони прави Общината организатор и по този начин избягва искането на позволение.

Става ли чрез тази маневра прайдът законен? Не, защото конституцията и законите имат приоритет над решенията на местната власт. Целта на кмета обаче е не да легализира събитието (това е отвъд правомощията му), а то да се проведе.

Освен това ЛГБТИ+ организациите и активистите са много по-лесна мишена на репресивни мерки, отколкото управата на столицата на една държава. Играейки вабанк, Карачони успява да постигне мирно протичане на събитието, без полицейско насилие и без значими провокации. (Казвам „без значими“, защото мой познат, присъствал на прайда в Будапеща, е видял нидерландец, държащ голям дървен кръст и крещящ на участниците колко са грешни.)

А в София?

В България прайдът продължава да не се разпознава като важен индикатор дори за либералната демокрация. 17 години след началото на дебата той продължава да е на ниво имат ли куиър хората право на съществуване и колко точно публично присъствие от тяхна страна не е „прекалено“.

Още преди да стане кмет на София, Васил Терзиев каза на среща с граждани, че „имаме нужда от „София прайд“ – мирно събитие, на което се събират много хора с деца“. Въпреки това Общината не само не участва в организацията на събитието, както е в много градове в други страни (например в САЩ, Канада, Франция, Нидерландия, Германия и др.), а и вече втора година Терзиев не е излязъл на сцената да поздрави участниците. За разлика от представителите на редица дипломатически мисии, които с присъствието си стават гаранти за мирното протичане на демонстрацията.

За сметка на това тази година програмата на „София прайд“ беше променена, за да не съвпадне провеждането на шествието с хомофобски събития, заявили в Общината обичайните за прайда маршрути. Имаше не едно, а две анти-ЛГБТИ+ мероприятия – „Шествие за семейството“, завършващо с концерт пред храм-паметника „Александър Невски“ и концерт „Традицията е бъдещето“ пред НДК.

Конституции за избирателна (зло)употреба

Вместо похвали и увеличена популярност Гергели Карачони не заслужава ли порицание, ако не и наказание, че умишлено и демонстративно е нарушил Конституцията на Унгария? Хващам се на бас, че повечето хора, които отправят този упрек срещу кмета на Будапеща, биха оправдали неспазването на конституцията в други случаи.

Когато например районният кмет на „Илинден“ Емил Бранчевски нареди разрушаването на ромската махала в кв. „Захарна фабрика“ и така остави около 200 души без дом, той наруши Конституцията на България. Защото в нея пише, че международните договори, които България е приела, са част от вътрешното законодателство и имат приоритет над него. А Европейският съд по правата на човека в Страсбург изрично е предупредил Бранчевски, че се кани да погази европейското законодателство. Той обаче се изкара герой, защото бил изпълнил… общинска заповед.

Какво да кажем за американския президент Доналд Тръмп, който си позволява да нарушава всеки текст от Конституцията на САЩ, ако не му изнася? За разлика от хомофобските промени в Основния закон на Унгария, които са съвсем скорошни, 14-тата поправка на Конституцията на САЩ, според която всеки, роден на американска земя, става гражданин на страната, датира от далечната 1868 година. Което не пречи на Тръмп на практика да не се съобразява с нея. И на милиони хора – да му ръкопляскат за това.

Конституционният съд и Върховният касационен съд в България пък тълкуват Основния закон, хиперболизирайки някои елементи в него. Основно – че бракът е между мъж и жена и че традиционната религия е православието. И системно не забелязват други – например че религиозните институции са отделени от държавата и не могат да се използват за политически цели. Така те изобретяват несъществуващи „правни традиции“.

Примерите с Карачони и Бранчевски всъщност показват колко важно може да е отношението на един кмет към конституцията.

В първия случай нарушаването ѝ от страна на кмета е в името на съхраняването на либералната демокрация, във втория – от популизъм и дискриминация. И двата случая предизвикват международен отзвук, макар и от различен порядък.

Кристиян Таков беше призовал да пазим правото – включително и от закона. Това важи с особена сила, когато се приемат противоправни и антидемократични закони. И конституционни промени.

Трябва да променим условията за упражняване на публична власт

Post Syndicated from Bozho original https://blog.bozho.net/blog/4488

Наследството от 45 години тоталитарен режим е държава, в която служби и прокуратура се използват за политически цели, а основните им функции са понякога на заден план. И в тази среда изтичането на записи, снимки, протоколи от разпити се сблъсква с разбираемото недоверие у избирателите и с усещането за “активни мероприятия”.

Такава е реакцията на всички партийни ядра. И това може да даде измамна увереност на политическите ръководства, че няма електорален проблем. Това е обобщение на база на множество примери в историята, като последните и най-ярки такива са при ГЕРБ – снимките с пачките и кюлчетата, записите “ще му размажа физиономията”, а преди това “Мишо Бирата”.

Реакцията на ГЕРБ и техните най-верни избиратели беше да се игнорира съдържанието и какво значи за нивото на изгнилост на институциите и да се постави фокус върху това дали записите и снимките са истински, кой ги е направил, откъде са изтекли, защо са изтекли и кой има интерес от тях. Но тогава една немалка част от периферията на ГЕРБ си тръгна. Не шумно, не с късане на ризи в социалните мрежи, но си тръгна на следващите избори.

И тъй като прокуратурата и антикорупционната комисия в последните години успешно си изградиха образа на бухалки на Пеевски, а „прихващането“ чрез морков и тояга е основен милиционерски похват, сега много хора в ядрото на общите ни избирателите с колегите от Продължаваме промяната са убедени, че това е скалъпен скандал. Поредното “активно мероприятие”. Задават се същите въпроси – дали записът е истински, кой го е правил, откъде е изтекъл, защо сега и кой има интерес.

В миналото за такива скандали отговорност не се е поемала. Сега Кирил Петков пое такава, което ние отчетохме като отговорното и разумно политическо действие. И то е именно такова, и то не само от вътрешнопартийна гледна точка.

Във всички такива случаи в историята, обаче, неглижирането на ситуацията винаги е носело вреди. И ще направим грешка, ако не си вземем поуки и не вземем мерки. Ако не направим вътрешни разследвания, ако не изкореним предпоставките за такива проблеми. Убеден съм, че колегите от ПП до своя форум през септември ще направят всичко това, за да бъдат премахнати съмненията в коалицията.

Защото докато част от избирателите смятат, че всичко е постановка, друга част очакват убедителен отговор на случилото се.

И накрая – борбата с корупцията. За да не просто изтъркан политически слоган – борбата с корупцията е битка за върховенство на закона, за независим съд и най-вече, за отчетна прокуратура, която разследва обективно и всестранно всички съмнения за злоупотреба с обществен ресурс. Всички, а не само тези, които бъдат посочени от текущия политически “север”, по който се ориентира компасът на главния прокурор и антикорупционната комисия.

В момента това е Пеевски. Или “Делян”, както казва Борисов. И именно затова “войната” с него в борисовите очи е страшна, защото следващите записи могат да са (пак) на Борисов, а досъдебните производства – срещу него и хората му. Отпадането на мерките за ограничаване на влиянието на Пеевски от коалиционното споразумение беше просто поредният пример за този страх. Това е и втората разлика с предишни записи – че наказателно преследване след тях е нямало.

Но е време да си дадем сметка, че най-ефективните политики с антикорупционен ефект върху публичния и частен сектор са десните политики. Когато намалиш преразпределението от държавата, когато намалиш административното регулиране, когато стимулираш пазарната конкуренция, когато повишиш прозрачността на администрацията, автоматично намаляваш корупционния риск. Илюзия е, че с повече държава и раздути бюджети, но с правилни хора начело, ще има значително по-малко корупция. Може временно да намалее, докато не се прегрупира и като река не намери нови пътища, през които да тече.

Доброто и злото са лични морални категории. И те са много важни за хода на историята. Но ние трябва да излезем от режима на политическо противопоставяне на база на морални категории. И вместо това да променим условията, при които се упражнява публична власт. Защото иначе репресивната машината винаги ще е в ръцете на някого, ще корумпира, ще мачка, ще изнудва, ще “сготвя”. И никой няма да е застрахован.

И даже това не е толкова страшно, колкото това, че никой няма да може да изгради доверие между политическите представители и хората и ще отвори широко портите за крайния популизъм и авторитаризма, пред сринатия смисъл от демократично представителство.

Нашата трудна политическа задача е да не позволим да се стигне дотам.

Материалът Трябва да променим условията за упражняване на публична власт е публикуван за пръв път на БЛОГодаря.

Begin your Code Club journey: Set up a club today

Post Syndicated from Lou Loxley original https://www.raspberrypi.org/blog/begin-your-code-club-journey-set-up-a-club-today/

Inspired to set up a Code Club but not sure where to start? In this blog we hear from the amazing network of Code Club leaders and mentors, and we give you practical tips on how to take the first steps to set up your own club. 

Two young coders at a Code Club.

About Code Club

Code Club is a thriving global community of clubs where young people can develop the confidence to create with digital technologies in a fun and supportive space. Code Clubs run in schools, libraries and other community settings. We have already supported 2 million school-aged young people worldwide to make things they care about with code.

We offer free training and ongoing support for anyone who would like to set up a Code Club — you don’t need to have a background in coding and technology to get involved.

Two teachers give their tips on setting up a Code Club

“If you’re thinking of starting a Code Club, do it. The Code Club team has everything created — all the resources are available.” – Peter Hutyan, Code Club mentor, The Mease Spencer Academy, UK. 

Peter, a primary school teacher, has been running a Code Club for seven years at The Mease Spencer Academy in Derby, UK.

A man smiling.

“When I started Code Club, I didn’t know how to do Scratch”, says Peter about the block-based coding tool that lots of young learners start with. “So I made myself learn how to use Scratch and I was two to three lessons ahead of the kids. Basically I’ve done what the kids will do — I’ve read the instructions and created the code. It’s such a phenomenal experience of enriching young people’s lives, and you see the smile and sense of accomplishment on their faces. It’s the best day ever.”

Rachael Coultart is the Computer Subject Leader at St Nicholas Primary School, Stevenage, UK and has run a Code Club for over ten years.

A woman laughing.

“I think the benefits of running a Code Club for our school are that it really develops children’s collaboration skills, really develops their perseverance, their thinking skills, their independence”, Rachael says. 

“The key ingredients that I think make a Code Club successful is enthusiasm, from the adults who are there, a kind of passion to learn together and make mistakes together. I kind of think that sets the scene for the children to make mistakes as well. And I think having that freedom outside the classroom is what makes a Code Club really successful.” – Rachael Coultart, Computing Subject Leader, St Nicholas Primary School, UK

Club mentors share why they were inspired to start a club

Saad Koubeissi runs four Code Clubs in libraries in London, UK.

A man smiling.

“Code Club, for me personally, is about providing children with things I didn’t have when I was younger”, says Saad. “I went to youth clubs and stuff but it was never, like, so specific in tech, it was more, like, playing football. So Code Club, I think, by starting off early, it’s introducing children not only to identifying those skills, but also the terminologies, providing that. And being able to be part of that change for those children is welcome for me, to be honest.” 

Bob Bisland is a mentor who started his first Code Club twelve years ago after a career in technology. He now runs three clubs in Malvern, UK.

A man smiling.

“Everyone should set up a Code Club. This is such a rewarding thing to be able to do. I am sharing my passion and my knowledge with another generation of children, and I’m seeing them learn what coding is all about.”

Ready to start? Three steps to set up a Code Club

We provide everything you need to make starting a club straightforward, including hundreds of free coding projects to help you tailor your sessions to the interests of your young tech creators. Our projects are available in up to 40 languages.

  1. Choose your venue. Code Clubs are held in lots of different places, such as schools, libraries and community centres.
  2. Register your club. Complete your application to start your club. We’ll ask for a few details, e.g. the address of your club. 
  3. Start running your club. You can access our free training on how to prepare to run a Code Club. Our Code Club leader guide also includes helpful information for running your club. 

Running a Code Club is a fun and rewarding way to engage young people and help them learn valuable skills for the future. Start your Code Club journey today by finding out more about setting up a club.

The post Begin your Code Club journey: Set up a club today appeared first on Raspberry Pi Foundation.

[$] LWN.net Weekly Edition for July 3, 2025

Post Syndicated from corbet original https://lwn.net/Articles/1026982/

Inside this week’s LWN.net Weekly Edition:

  • Front: Kernel features from Python; i686 in Fedora; Kernel development with LLMs; Rust drivers; Load balancing with machine learning; Transparent huge pages.
  • Briefs: Bcachefs removal; Coccinelle for Rust; Netdev Foundation; Oracle Linux 10; GNU HHIS 5.0; Rust 1.88.0; Quotes; …
  • Announcements: Newsletters, conferences, security updates, patches, and more.

Amazon Nova Canvas update: Virtual try-on and style options now available

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/amazon-nova-canvas-update-virtual-try-on-and-style-options-now-available/

Have you ever wished you could quickly visualize how a new outfit might look on you before making a purchase? Or how a piece of furniture would look in your living room? Today, we’re excited to introduce a new virtual try-on capability in Amazon Nova Canvas that makes this possible. In addition, we are adding eight new style options for improved style consistency for text-to-image based style prompting. These features expand Nova Canvas AI-powered image generation capabilities making it easier than ever to create realistic product visualizations and stylized images that can enhance the experience of your customers.

Let’s take a quick look at how you can start using these today.

Getting started
The first thing is to make sure that you have access to the Nova Canvas model through the usual means. Head to the Amazon Bedrock console, choose Model access and enable Amazon Nova Canvas for your account making sure that you select the appropriate regions for your workloads. If you already have access and have been using Nova Canvas, you can start using the new features immediately as they’re automatically available to you.

Virtual try-on
The first exciting new feature is virtual try-on. With this, you can upload two pictures and ask Amazon Nova Canvas to put them together with realistic results. These could be pictures of apparel, accessories, home furnishings, and any other products including clothing. For example, you can provide the picture of a human as the source image and the picture of a garment as the reference image, and Amazon Nova Canvas will create a new image with that same person wearing the garment. Let’s try this out!

My starting point is to select two images. I picked one of myself in a pose that I think would work well for a clothes swap and a picture of an AWS-branded hoodie.

Matheus and AWS-branded hoodie

Note that Nova Canvas accepts images containing a maximum of 4.1M pixels – the equivalent of 2,048 x 2,048 – so be sure to scale your images to fit these constraints if necessary. Also, if you’d like to run the Python code featured in this article, ensure you have Python 3.9 or later installed as well as the Python packages boto3 and pillow.

To apply the hoodie to my photo, I use the Amazon Bedrock Runtime invoke API. You can find full details on the request and response structures for this API in the Amazon Nova User Guide. The code is straightforward, requiring only a few inference parameters. I use the new taskType of "VIRTUAL_TRY_ON". I then specify the desired settings, including both the source image and reference image, using the virtualTryOnParams object to set a few required parameters. Note that both images must be converted to Base64 strings.

import base64


def load_image_as_base64(image_path): 
   """Helper function for preparing image data."""
   with open(image_path, "rb") as image_file:
      return base64.b64encode(image_file.read()).decode("utf-8")


inference_params = {
   "taskType": "VIRTUAL_TRY_ON",
   "virtualTryOnParams": {
      "sourceImage": load_image_as_base64("person.png"),
      "referenceImage": load_image_as_base64("aws-hoodie.jpg"),
      "maskType": "GARMENT",
      "garmentBasedMask": {"garmentClass": "UPPER_BODY"}
   }
}

Nova Canvas uses masking to manipulate images. This is a technique that allows AI image generation to focus on specific areas or regions of an image while preserving others, similar to using painter’s tape to protect areas you don’t want to paint.

You can use three different masking modes, which you can choose by setting maskType to the correct value. In this case, I’m using "GARMENT", which requires me to specify which part of the body I want to be masked. I’m using "UPPER_BODY" , but you can use others such as "LOWER_BODY", "FULL_BODY", or "FOOTWEAR" if you want to specifically target the feet. Refer to the documentation for a full list of options.

I then call the invoke API, passing in these inference arguments and saving the generated image to disk.

# Note: The inference_params variable from above is referenced below.

import base64
import io
import json

import boto3
from PIL import Image

# Create the Bedrock Runtime client.
bedrock = boto3.client(service_name="bedrock-runtime", region_name="us-east-1")

# Prepare the invocation payload.
body_json = json.dumps(inference_params, indent=2)

# Invoke Nova Canvas.
response = bedrock.invoke_model(
   body=body_json,
   modelId="amazon.nova-canvas-v1:0",
   accept="application/json",
   contentType="application/json"
)

# Extract the images from the response.
response_body_json = json.loads(response.get("body").read())
images = response_body_json.get("images", [])

# Check for errors.
if response_body_json.get("error"):
   print(response_body_json.get("error"))

# Decode each image from Base64 and save as a PNG file.
for index, image_base64 in enumerate(images):
   image_bytes = base64.b64decode(image_base64)
   image_buffer = io.BytesIO(image_bytes)
   image = Image.open(image_buffer)
   image.save(f"image_{index}.png")

I get a very exciting result!

Matheus wearing AWS-branded hoodie

And just like that, I’m the proud wearer of an AWS-branded hoodie!

In addition to the "GARMENT" mask type, you can also use the "PROMPT" or "IMAGE" masks. With "PROMPT", you also provide the source and reference images, however, you provide a natural language prompt to specify which part of the source image you’d like to be replaced. This is similar to how the "INPAINTING" and "OUTPAINTING" tasks work in Nova Canvas. If you want to use your own image mask, then you choose the "IMAGE" mask type and provide a black-and-white image to be used as mask, where black indicates the pixels that you want to be replaced on the source image, and white the ones you want to preserve.

This capability is specifically useful for retailers. They can use it to help their customers make better purchasing decisions by seeing how products look before buying.

Using style options
I’ve always wondered what I would look like as an anime superhero. Previously, I could use Nova Canvas to manipulate an image of myself, but I would have to rely on my good prompt engineering skills to get it right. Now, Nova Canvas comes with pre-trained styles that you can apply to your images to get high-quality results that follow the artistic style of your choice. There are eight available styles including 3D animated family film, design sketch, flat vector illustration, graphic novel, maximalism, midcentury retro, photorealism, and soft digital painting.

Applying them is as straightforward as passing in an extra parameter to the Nova Canvas API. Let’s try an example.

I want to generate an image of an AWS superhero using the 3D animated family film style. To do this, I specify a taskType of "TEXT_IMAGE" and a textToImageParams object containing two parameters: text and style. The text parameter contains the prompt describing the image I want to create which in this case is “a superhero in a yellow outfit with a big AWS logo and a cape.” The style parameter specifies one of the predefined style values. I’m using "3D_ANIMATED_FAMILY_FILM" here, but you can find the full list in the Nova Canvas User Guide.

inference_params = {
   "taskType": "TEXT_IMAGE",
   "textToImageParams": {
      "text": "a superhero in a yellow outfit with a big AWS logo and a cape.",
      "style": "3D_ANIMATED_FAMILY_FILM",
   },
   "imageGenerationConfig": {
      "width": 1280,
      "height": 720,
      "seed": 321
   }
}

Then, I call the invoke API just as I did in the previous example. (The code has been omitted here for brevity.) And the result? Well, I’ll let you judge for yourself, but I have to say I’m quite pleased with the AWS superhero wearing my favorite color following the 3D animated family film style exactly as I envisioned.

What’s really cool is that I can keep my code and prompt exactly the same and only change the value of the style attribute to generate an image in a completely different style. Let’s try this out. I set style to PHOTOREALISM.

inference_params = { 
   "taskType": "TEXT_IMAGE", 
   "textToImageParams": { 
      "text": "a superhero in a yellow outfit with a big AWS logo and a cape.",
      "style": "PHOTOREALISM",
   },
   "imageGenerationConfig": {
      "width": 1280,
      "height": 720,
      "seed": 7
   }
}

And the result is impressive! A photorealistic superhero exactly as I described, which is a far departure from the previous generated cartoon and all it took was changing one line of code.

Things to know
Availability – Virtual try-on and style options are available in Amazon Nova Canvas in the US East (N. Virginia), Asia Pacific (Tokyo), and Europe (Ireland). Current users of Amazon Nova Canvas can immediately use these capabilities without migrating to a new model.

Pricing – See the Amazon Bedrock pricing page for details on costs.

For a preview of virtual try-on of garments, you can visit nova.amazon.com where you can upload an image of a person and a garment to visualize different clothing combinations.

If you are ready to get started, please check out the Nova Canvas User Guide or visit the AWS Console.

Matheus Guimaraes | @codingmatheus

Where and Why Object Storage Excels Throughout the AI Model Lifecycle

Post Syndicated from David Johnson original https://www.backblaze.com/blog/where-and-why-object-storage-excels-throughout-the-ai-model-lifecycle/

A decorative image showing a multi-paned screen backed up by a cloud.

No single technology has changed the way we use data quite like AI. From massive training sets to constant streams of checkpoint and inference data, AI applications are data intensive, to say the least.
Thankfully, there’s an answer. Object storage—with its scalability, flexibility, and cost-effectiveness—is uniquely suited to AI at every stage of the model lifecycle.

In this blog post, we’ll take a quick look at what object storage is, why it’s a perfect fit for AI workloads, and how Backblaze B2 Cloud Storage offers unique advantages for AI teams looking to innovate quickly, easily, and cost-effectively.

What is object storage?

Think of object storage as a giant, organized bucket for all your files. Instead of stuffing things into folders or breaking them into blocks, you just drop each file (an “object”), with a unique tag and some helpful notes (metadata), into your storage solution.

Unlike traditional file or block storage, object storage uses a flat address space. Each object is assigned a unique identifier and can be tagged with rich metadata, making it easy to search, retrieve, and manage at scale.

Because of this unique architecture, object storage is ideal for handling unstructured data—such as images, video, audio, text, and sensor data—which is the meat and potatoes of most modern AI workflows. Also, being cloud-based, object storage is inherently designed for massive scalability and accessibility over the internet (often via S3 API).

Ebook: “Why Object Storage Is Ideal for AI Workflows”

Want to take a deeper dive into the world of object storage? Check out our latest ebook, “Why Object Storage is Ideal for AI Workloads,” and discover the advantages this architecture has to offer across the model lifecycle.

Get the Ebook

Understanding AI’s data storage needs at each stage of the model lifecycle

Before diving into the benefits of object storage, let’s first define and outline the AI model lifecycle. While some may slice and dice it a little differently, generally speaking, we can break the AI model lifecycle down into the following stages:

  • Data ingestion and collection: Massive, often petabyte-scale datasets are gathered from a diversity of sources.
  • Data preparation and storage: Raw data is cleaned, labeled, transformed, and stored for future retrieval and processing.
  • Model training: Data is fed into AI training algorithms, typically deployed across many nodes in a GPU cluster—usually requiring high throughput, parallel access, and lengthy processing times.
  • Deployment and inference: Trained models are deployed into live applications where they take in new data and make inferences based on that data.
  • Monitoring and archiving: Continuous monitoring generates substantial amounts of log data and performance metrics that must be versioned, stored, and archived for compliance or retraining purposes.

As you can see, each stage of the model lifecycle presents its own unique set of data demands—with each one requiring plenty of planning, work, and preparation. And at every one of these stages, matters of scale, speed, accessibility, and cost are mission-critical to a project’s success. 

Where object storage excels: Scalability for data ingestion and collection

Object storage offers virtually unlimited scalability for large, and ever-expanding datasets, making it an ideal solution for the earliest stages of AI development. With no need to create volumes or file systems, organizations can quickly start uploading data to object storage. In addition to this seamless scalability, object storage also shines in its ability to support a diverse range of structured and unstructured data types without the need for rigid hierarchies. In this way, AI teams can ingest all sorts of data to support whatever their unique application needs; and do it quickly and efficiently.

Flexible data preparation and storage

Cloud-based object storage systems are excellent for maintaining easily-accessible, version-controlled datasets that allow for lightning fast iteration and collaboration. Capabilities like version recovery (which allows teams to easily revert datasets to previous states with simple API calls) and concurrent access (which gives multiple team members the ability to work on the same datasets simultaneously without conflicts) are also key to the data preparation and storage phase of AI development.

Reliable, high-performance data storage for model training

For the model training stage of the AI lifecycle, object storage supports parallel access and high throughput, both of which are absolutely essential for GPU-intensive training workloads. Reliable shuttling of large datasets to GPU clusters, wherever they may be, is key for keeping things efficient. Meanwhile, streamlined storage of model checkpoints from those clusters gives teams peace of mind in knowing that a mid-training failure state will not place them all the way back at square one.

Plus, lifecycle management features allow completed or outdated training datasets to be automatically archived—reducing clutter and optimizing storage costs, all while keeping active training data easily accessible.

Efficient versioning for deployment and inference

AI models are always a work in progress. Once deployed and operational, they have to be routinely evaluated and tuned. To that end, object storage makes it easy to store and retrieve a range of valuable information, including model checkpoints, test results, and inference data.

Built-in versioning and object immutability features support reproducibility and audit trails, so you can always trace which data and models produced which results. Together, these capabilities make for robust and effective lifecycle management, significantly boosting reliability and compliance.

Cost-effectiveness and durability for monitoring and archiving

When in the field, continuous monitoring of AI models generates a whole lot of log data and performance metrics. Object storage automates the management of these resources through customizable lifecycle rules, automatically deleting or archiving out-of-date inference logs based on predefined timelines (e.g., after 30–180 days).

This significantly reduces the need for manual oversight, conserves engineering resources, and ensures that relevant performance data remains accessible for compliance and regulatory auditing.

Meanwhile, with the right vendor, object storage solutions can offer competitive pricing models—sometimes including the separation of compute from storage—to ensure cost-effectiveness throughout the late stages of the AI lifecycle. Finally, high durability (of 11 nines or more) and redundancies protect models and datasets which become increasingly valuable over time.

Backblaze B2: Cost-effective, high-performance object storage for your AI workloads

Backblaze B2 Cloud Storage takes all the inherent advantages of cloud-based object storage for AI workloads and amplifies them—through competitive, transparent pricing; reliable, high performance; and seamless integration and support to ensure your project is not only efficient and affordable, but most importantly, successful. 

  • Competitive, transparent pricing: One-fifth of the cost of most hyperscalers’ solutions, with no hidden costs and three times your total storage volume in free egress included. Plus, fully-transparent, predictable pricing models ensure your organization is fully aware and prepared for the costs associated with your applications. 
  • High performance and reliability: Upload speeds up to 30% faster than AWS S3 for many workloads, plus a 99.9% uptime SLA with 11 nines of durability, ensure always-hot, instantly accessible data for demanding AI workloads. 
  • Seamless adoption and integration, accompanied by expert support: With features like Universal Data Migration and no hidden delete fees, B2 Cloud Storage uniquely streamlines cost-effective data management for AI. Backblaze B2 also boasts S3 API compatibility for true plug-and-play functionality with leading AI and machine learning ops (MLOps) tools and technologies.

Plus, our truly agnostic solution allows organizations to freely and easily connect to any compute or GPU environment (or environments), free of vendor lock-in and fees. And in case you want some support along the way, our team of dedicated solution engineers are available to tailor and fine-tune your architecture and operations to best suit whatever the unique needs of your AI project may be. 

Optimize your AI lifecycle with cloud object storage from Backblaze B2

Data is one of the most important, and most challenging, aspects of AI development. And with their unprecedented data demands, traditional block and file storage systems frequently come up short in supporting modern AI applications. At the same time, legacy cloud storage solutions come with enormous burdens of cost, inflexibility, and the ever-looming threat of lock-in.

Cloud-based object storage offers the perfect solution to all these challenges—with the right mixture of performance, efficiency, and cost-effectiveness that AI projects need.It’s so-well-suited, in fact, that we’ve written an entire white paper on the subject! So, if you’re interested in taking a deeper dive into the topic, check out our ebook, Why Object Storage is Ideal for AI Workloads, today.

The post Where and Why Object Storage Excels Throughout the AI Model Lifecycle appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

The collective thoughts of the interwebz