Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/kjT4cm0l1t8
Implementing message prioritization with quorum queues on Amazon MQ for RabbitMQ
Post Syndicated from Akhil Melakunta original https://aws.amazon.com/blogs/compute/implementing-message-prioritization-with-quorum-queues-on-amazon-mq-for-rabbitmq/
Quorum queues are now available on Amazon MQ for RabbitMQ from version 3.13. Quorum queues are a replicated First-In, First-Out (FIFO) queue type that uses the Raft consensus algorithm to maintain data consistency. Quorum queues on RabbitMQ version 3.13 lack one key feature compared to classic queues: message prioritization. However, RabbitMQ version 4.0 introduced support for message priority, which behaves differently than classic queue message priorities. Migrating applications from classic queues with message priority to quorum queues on Amazon MQ for RabbitMQ presents challenges for customers. This post describes the different approaches to implementing message prioritization in quorum queues in Amazon MQ for RabbitMQ.
Amazon MQ is a managed message broker service for Apache ActiveMQ and RabbitMQ that simplifies setting up and operating message brokers on AWS.
Why message prioritization matters
Modern messaging systems require handling messages differently, depending on the business priority. Some messages are more time-sensitive or critical than others and prioritizing them can enhance the efficiency and responsiveness of applications. Message prioritization allows certain messages to be processed before others, aligning with business priorities and helping to ensure that high-value or time-critical messages receive the attention they need.
Message prioritization addresses critical business challenges across multiple industries. In insurance companies, it can expedite urgent claim processing by prioritizing high-priority messages over routine policy updates, reducing settlement times. Automotive manufacturers can make sure that critical production line alerts and safety notifications take precedence over standard telemetry data, preventing costly downtime. Energy utilities can prioritize real-time grid stability alerts and outage notifications, enabling faster responses to potential blackouts. By implementing message priority, industries can direct immediate attention to time-sensitive operations while efficiently managing routine processes within existing infrastructure. By using this approach to transform their communication strategies, organizations can respond more quickly and effectively to critical events.
Classic queues compared to quorum queues message prioritization
In this section, explore the fundamental differences between classic queues and quorum queues when it comes to message prioritization capabilities. Examine how each queue type handles message priority, the built-in features available, and key considerations.
Message prioritization with classic queues
In classic queues, RabbitMQ supports message priorities ranging from 1 to 255, with 1 being the lowest priority and 255 being the highest. However, it’s generally recommended to use a smaller range (for example, 1–5) for better performance, because RabbitMQ needs to maintain an internal sub-queue for each priority from 1 up to the maximum value configured for a given queue. A wider priority range adds more CPU and memory cost, which can impact broker performance.
Priority queue behavior in classic queues:
- Classic queues require
x-max-priorityargument to define the maximum number of priorities for a given queue - A procedure sends a message with a priority property value
- Consumers don’t need special configuration to handle priorities
- Messages with higher priority are delivered before messages with lower priority
- Within the same priority level, messages are delivered in FIFO order
- Messages without a priority property are treated as if their priority is lowest
- Messages with a priority that is higher than the queue’s maximum are treated as if they were published with the maximum priority
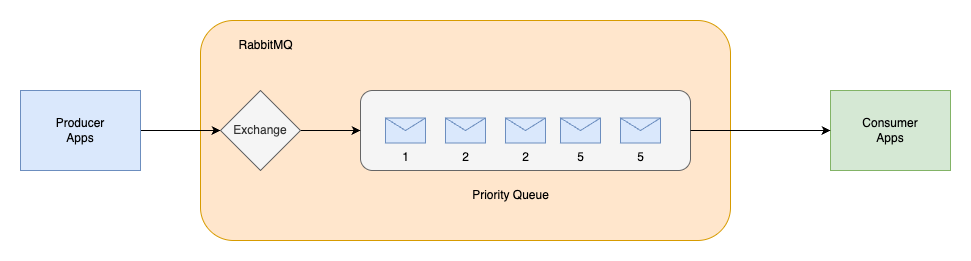
Example Python code for classic queue implementation with message priority:
The preceding code demonstrates message prioritization in RabbitMQ using a classic queue with built-in priority handling. The implementation connects to a RabbitMQ broker using the Python Pika library and declares a direct exchange, a classic queue with a maximum priority level of 5. Messages are then published to this single queue with explicitly assigned priority values (1 for low, 2 for medium, and 5 for high priority). When consumers fetch messages from this queue, RabbitMQ will deliver higher priority messages first.
Message prioritization with quorum queues
Unlike classic queues, quorum queues in Rabbit MQ 3.13 don’t support message prioritization natively. However, there are effective patterns that you can implement to achieve message priority with Quorum queues.
Using separate queues for different priorities
A straightforward method is to create multiple quorum queues, each dedicated to different priority levels. For example, you might have a high-priority queue and a low-priority queue. Using RabbitMQ exchange and binding key route messages to the appropriate queues based on their priority, allowing the system to process high-priority messages more promptly, as shown in the following figure.
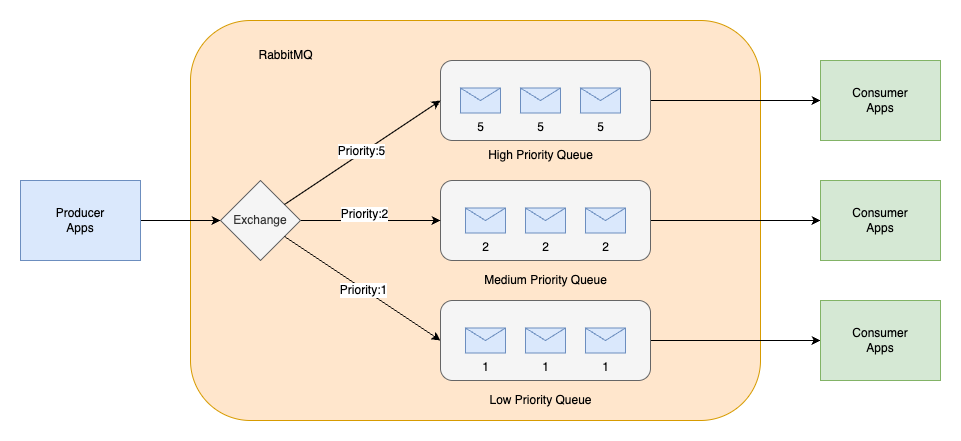
Example to implement priority handling using separate quorum queues:
The preceding code demonstrates a message prioritization approach in RabbitMQ using separate quorum queues for different priority levels (low, medium, and high). The implementation uses the Python Pika library to connect to a RabbitMQ server, a direct exchange and three separate quorum queues for different priority levels, and publish messages to different routing keys with different priority.
Custom priority logic on consumers
Implement custom logic within your application to handle messages based on their priority. For example, you can use headers or metadata to determine the priority of a message and then use this information to route messages to different queues or handle them in a specific order.
Higher priority queues should use more consumers or consumers with higher resources allocated to process messages more quickly than lower priority queues. Use the basic.qos (prefetch) method in manual acknowledgement mode on your consumers to limit the number of messages that can be out for delivery at any time and allow messages to be prioritized. basic.qos is a value a consumer sets when connecting to a queue. It indicates how many messages the consumer can handle at one time. This method is shown in the following figure.
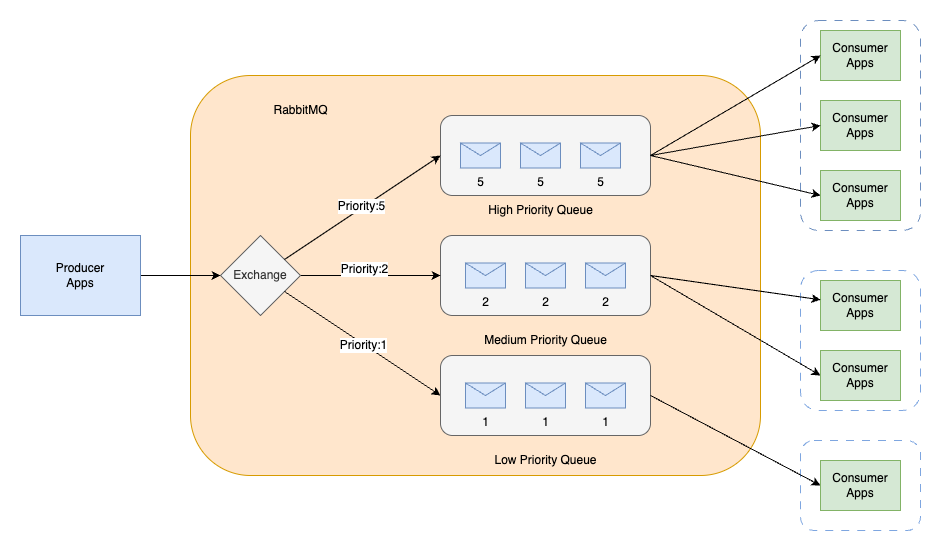
Note: This solution implements message priority on a best-effort basis. There is a possibility that low and medium priority messages may be processed before high priority messages.
Conclusion
Message prioritization in RabbitMQ brokers on Amazon MQ has different considerations for classic and quorum queues. Using quorum queues requires a thoughtful approach because of the lack of native support for message proritization in RabbitMQ. By employing separate queues and custom logic, you can achieve effective prioritization while maintaining the high availability and consistency that quorum queues offer. Embrace these strategies to optimize your messaging infrastructure, enhance application responsiveness, and make sure that critical messages are processed in a timely manner.
We recommend that you adopt quorum queues as the preferred replicated queue type on RabbitMQ 3.13 brokers. For more details, see Amazon MQ documentation. For more information, see quorum queues.
To learn more, see Amazon MQ for Rabbit MQ.
New whitepaper available: AICPA SOC 2 Compliance Guide on AWS
Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/new-whitepaper-available-aicpa-soc-2-compliance-guide-on-aws/
We’re excited to announce the release of our latest whitepaper, AICPA SOC 2 Compliance Guide on AWS, which provides in-depth guidance on implementing and maintaining SOC 2-aligned controls using AWS services.
Building and operating cloud-native services in alignment with the AICPA’s Trust Services Criteria requires thoughtful planning and robust implementation. This new whitepaper helps cloud architects, security and compliance teams, and DevOps professionals design environments that meet SOC 2 requirements while leveraging AWS’s shared responsibility model.
What’s inside the whitepaper:
- Overview of the SOC 2 framework—including Common Criteria (CC 1–CC 9) and category-specific criteria (Security, Availability, Processing Integrity, Confidentiality, Privacy)
- Mapping of each Trust Services Criterion to AWS services and constructs
- Guidance on implementing complementary user entity controls (CUECs)
- Strategies for evidence collection, documentation, and audit procedures
- Risk and governance for executives
- Best practices for automating compliance and preparing for SOC 2 readiness assessments
Download AICPA SOC 2 Compliance Guide on AWS.
For further assistance, contact AWS Security Assurance Services.
If you have feedback about this post, submit comments in the Comments section below.
Introducing MCP Server for Apache Spark History Server for AI-powered debugging and optimization
Post Syndicated from Manabu McCloskey original https://aws.amazon.com/blogs/big-data/introducing-mcp-server-for-apache-spark-history-server-for-ai-powered-debugging-and-optimization/
Organizations running Apache Spark workloads, whether on Amazon EMR, AWS Glue, Amazon Elastic Kubernetes Service (Amazon EKS), or self-managed clusters, invest countless engineering hours in performance troubleshooting and optimization. When a critical extract, transform, and load (ETL) pipeline fails or runs slower than expected, engineers end up spending hours navigating through multiple interfaces such as logs or Spark UI, correlating metrics across different systems and manually analyzing execution patterns to identify root causes. Although Spark History Server provides detailed telemetry data, including job execution timelines, stage-level metrics, and resource consumption patterns, accessing and interpreting this wealth of information requires deep expertise in Spark internals and navigating through multiple interconnected web interface tabs.
Today, we’re announcing the open source release of Spark History Server MCP, a specialized Model Context Protocol (MCP) server that transforms this workflow by enabling AI assistants to access and analyze your existing Spark History Server data through natural language interactions. This project, developed collaboratively by AWS open source and Amazon SageMaker Data Processing, turns complex debugging sessions into conversational interactions that deliver faster, more accurate insights without requiring changes to your current Spark infrastructure. You can use this MCP server with your self-managed or AWS managed Spark History Servers to analyze Spark applications running in the cloud or on-premises deployments.
Understanding Spark observability challenge
Apache Spark has become the standard for large-scale data processing, powering critical ETL pipelines, real-time analytics, and machine learning (ML) workloads across thousands of organizations. Building and maintaining Spark applications is, however, still an iterative process, where developers spend significant time testing, optimizing, and troubleshooting their code. Spark application developers focused on data engineering and data integration use cases often encounter significant operational challenges due to a few different reasons:
- Complex connectivity and configuration options to a variety of resources with Spark – Although this makes it a popular data processing platform, it often makes it challenging to find the root cause of inefficiencies or failures when Spark configurations aren’t optimally or correctly configured.
- Spark’s in-memory processing model and distributed partitioning of datasets across its workers – Although good for parallelism, this often makes it difficult for users to identify inefficiencies. This results in slow application execution or root cause of failures caused by resource exhaustion issues such as out of memory and disk exceptions.
- Lazy evaluation of Spark transformations – Although lazy evaluation optimizes performance, it makes it challenging to accurately and quickly identify the application code and logic that caused the failure from the distributed logs and metrics emitted from different executors.
Spark History Server
Spark History Server provides a centralized web interface for monitoring completed Spark applications, serving comprehensive telemetry data including job execution timelines, stage-level metrics, task distribution, executor resource consumption, and SQL query execution plans. Although Spark History Server assists developers for performance debugging, code optimization, and capacity planning, it still has challenges:
- Time-intensive manual workflows – Engineers spend hours navigating through the Spark History Server UI, switching between multiple tabs to correlate metrics across jobs, stages, and executors. Engineers must constantly switch between the Spark UI, cluster monitoring tools, code repositories, and documentation to piece together a complete picture of application performance, which often takes days.
- Expertise bottlenecks – Effective Spark debugging requires deep understanding of execution plans, memory management, and shuffle operations. This specialized knowledge creates dependencies on senior engineers and limits team productivity.
- Reactive problem-solving – Teams typically discover performance issues only after they impact production systems. Manual monitoring approaches don’t scale to proactively identify degradation patterns across hundreds of daily Spark jobs.
How MCP transforms Spark observability
The Model Context Protocol provides a standardized interface for AI agents to access domain-specific data sources. Unlike general-purpose AI assistants operating with limited context, MCP-enabled agents can access technical information about specific systems and provide insights based on actual operational data rather than generic recommendations.With the help of Spark History Server accessible through MCP, instead of manually gathering performance metrics from multiple sources and correlating them to understand application behavior, engineers can engage with AI agents that have direct access to all Spark execution data. These agents can analyze execution patterns, identify performance bottlenecks, and provide optimization recommendations based on actual job characteristics rather than general best practices.
Introduction to Spark History Server MCP
The Spark History Server MCP is a specialized bridge between AI agents and your existing Spark History Server infrastructure. It connects to one or more Spark History Server instances and exposes their data through standardized tools that AI agents can use to retrieve application metrics, job execution details, and performance data.
Importantly, the MCP server functions purely as a data access layer, enabling AI agents such as Amazon Q Developer CLI, Claude desktop, Strands Agents, LlamaIndex, and LangGraph to access and reason about your Spark data. The following diagram shows this flow.
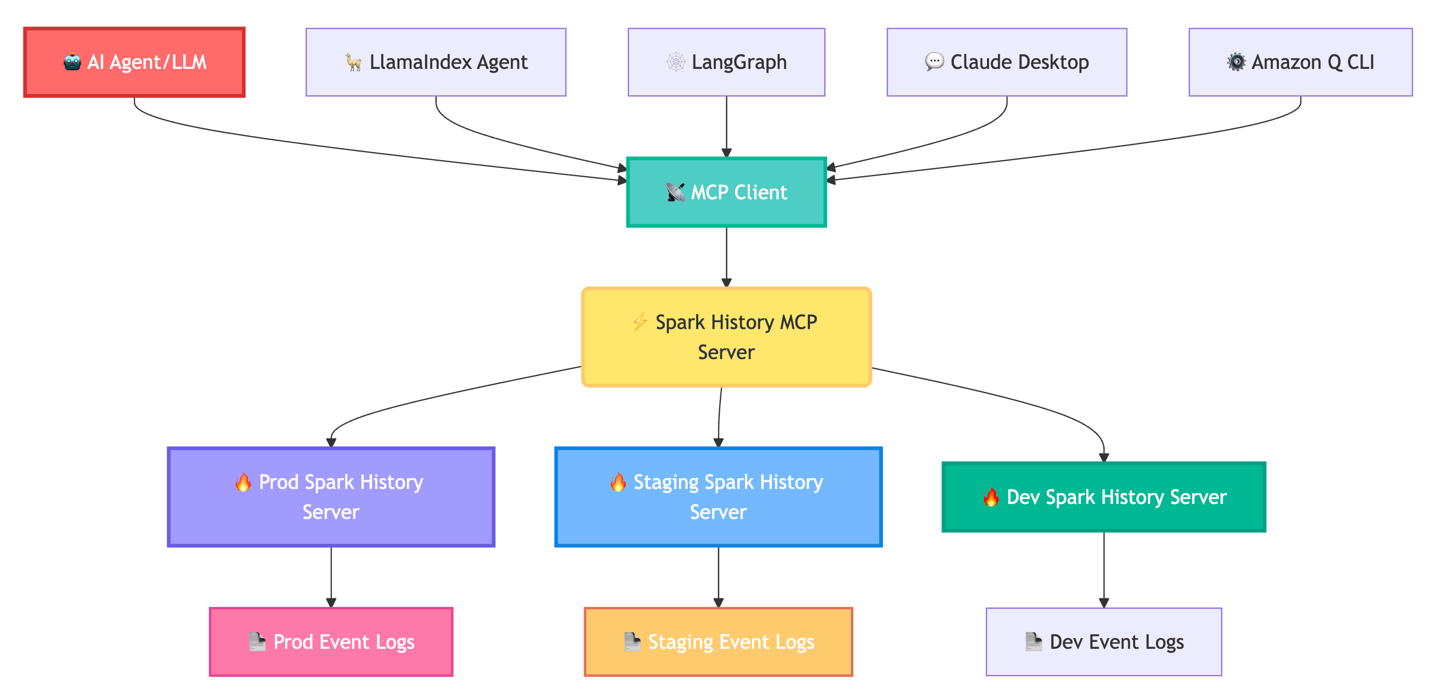
The Spark History Server MCP directly addresses these operational challenges by enabling AI agents to access Spark performance data programmatically. This transforms the debugging experience from manual UI navigation to conversational analysis. Instead of hours in the UI, ask, “Why did job spark-abcd fail?” and receive root cause analysis of the failure. This allows users to use AI agents for expert-level performance analysis and optimization recommendations, without requiring deep Spark expertise.
The MCP server provides comprehensive access to Spark telemetry across multiple granularity levels. Application-level tools retrieve execution summaries, resource utilization patterns, and success rates across job runs. Job and stage analysis tools provide execution timelines, stage dependencies, and task distribution patterns for identifying critical path bottlenecks. Task-level tools expose executor resource consumption patterns and individual operation timings for detailed optimization analysis. SQL-specific tools provide query execution plans, join strategies, and shuffle operation details for analytical workload optimization. You can review the complete set of tools available in the MCP server in the project README.
How to use the MCP server
The MCP is an open standard that enables secure connections between AI applications and data sources. This MCP server implementation supports both Streamable HTTP and STDIO protocols for maximum flexibility.
The MCP server runs as a local service within your infrastructure either on Amazon Elastic Compute Cloud (Amazon EC2) or Amazon EKS, connecting directly to your Spark History Server instances. You maintain complete control over data access, authentication, security, and scalability.
All the tools are available with streamable HTTP and STDIO protocol:
- Streamable HTTP – Full advanced tools for LlamaIndex, LangGraph, and programmatic integrations
- STDIO mode – Core functionality of Amazon Q CLI and Claude Desktop
For deployment, it supports multiple Spark History Server instances and provides deployments with AWS Glue, Amazon EMR, and Kubernetes.
Quick local setup
To set up Spark History MCP server locally, execute the following commands in your terminal:
For comprehensive configuration examples and integration guides, refer to the project README.
Integration with AWS managed services
The Spark History Server MCP integrates seamlessly with AWS managed services, offering enhanced debugging capabilities for Amazon EMR and AWS Glue workloads. This integration adapts to various Spark History Server deployments available across these AWS managed services while providing a consistent, conversational debugging experience:
- AWS Glue – Users can use the Spark History Server MCP integration with self-managed Spark History Server on an EC2 instance or launch locally using Docker container. Setting up the integration is straightforward. Follow the step-by-step instructions in the README to configure the MCP server with your preferred Spark History Server deployment. Using this integration, AWS Glue users can analyze AWS Glue ETL job performance regardless of their Spark History Server deployment approach.
- Amazon EMR – Integration with Amazon EMR uses the service-managed Persistent UI feature for EMR on Amazon EC2. The MCP server requires only an EMR cluster Amazon Resource Name (ARN) to discover the available Persistent UI on the EMR cluster or automatically configure a new one for cases its missing with token-based authentication. This eliminates the need for manually configuring Spark History Server setup while providing secure access to detailed execution data from EMR Spark applications. Using this integration, data engineers can ask questions about their Spark workloads, such as “Can you get job bottle neck for spark-<emr-applicationId>? ” The MCP responds with detailed analysis of execution patterns, resource utilization differences, and targeted optimization recommendations, so teams can fine-tune their Spark applications for optimal performance across AWS services.
For comprehensive configuration examples and integration details, refer to the AWS Integration Guides.
Looking ahead: The future of AI-assisted Spark optimization
This open-source release establishes the foundation for enhanced AI-powered Spark capabilities. This project establishes the foundation for deeper integration with AWS Glue and Amazon EMR to simplify the debugging and optimization experience for customers using these Spark environments. The Spark History Server MCP is open source under the Apache 2.0 license. We welcome contributions including new tool extensions, integrations, documentation improvements, and deployment experiences.
Get started today
Transform your Spark monitoring and optimization workflow today by providing AI agents with intelligent access to your performance data.
- Explore the GitHub repository
- Review the comprehensive README for setup and integration instructions
- Join discussions and submit issues for enhancements
- Contribute new features and deployment patterns
Acknowledgment: A special thanks to everyone who contributed to the development and open-sourcing of the Apache Spark history server MCP: Vaibhav Naik, Akira Ajisaka, Rich Bowen, Savio Dsouza.
About the authors
 Manabu McCloskey is a Solutions Architect at Amazon Web Services. He focuses on contributing to open source application delivery tooling and works with AWS strategic customers to design and implement enterprise solutions using AWS resources and open source technologies. His interests include Kubernetes, GitOps, Serverless, and Souls Series.
 Vara Bonthu is a Principal Open Source Specialist SA leading Data on EKS and AI on EKS at AWS, driving open source initiatives and helping AWS customers to diverse organizations. He specializes in open source technologies, data analytics, AI/ML, and Kubernetes, with extensive experience in development, DevOps, and architecture. Vara focuses on building highly scalable data and AI/ML solutions on Kubernetes, enabling customers to maximize cutting-edge technology for their data-driven initiatives
 Andrew Kim is a Software Development Engineer at AWS Glue, with a deep passion for distributed systems architecture and AI-driven solutions, specializing in intelligent data integration workflows and cutting-edge feature development on Apache Spark. Andrew focuses on re-inventing and simplifying solutions to complex technical problems, and he enjoys creating web apps and producing music in his free time.
 Shubham Mehta is a Senior Product Manager at AWS Analytics. He leads generative AI feature development across services such as AWS Glue, Amazon EMR, and Amazon MWAA, using AI/ML to simplify and enhance the experience of data practitioners building data applications on AWS.
 Kartik Panjabi is a Software Development Manager on the AWS Glue team. His team builds generative AI features for the Data Integration and distributed system for data integration.
 Mohit Saxena is a Senior Software Development Manager on the AWS Data Processing Team (AWS Glue and Amazon EMR). His team focuses on building distributed systems to enable customers with new AI/ML-driven capabilities to efficiently transform petabytes of data across data lakes on Amazon S3, databases and data warehouses on the cloud.
Discovering and recovering from PostgreSQL corruption on Matrix.org
Post Syndicated from jzb original https://lwn.net/Articles/1031148/
Richard van der Hoff, a member of the team that runs the Matrix.org homeserver,
has written
a detailed blog post about diagnosing and fixing a problem where Matrix rooms
would simply stop working:
We know that there are plenty of users out there who will have been
affected by the problem, and found themselves unable to communicate as
a result. We very much share your frustration, and we’d like to
apologise for the disruption to service.With that said, we’re glad that we were able to get to the bottom
of most of the problem, and get the lost data restored within a
relatively short time. If nothing else, hopefully this blog post will
be of use to future generations faced with Postgres index
corruption!
Is the Netgate 8300 Fast Enough For You?
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/shorts/NIT9mZFygQ0
[$] Understanding Debian’s security processes
Post Syndicated from jzb original https://lwn.net/Articles/1030669/
Providing security updates for a Linux distribution, such as
Debian, involves a lot of work behind the scenes—and requires
much more than simply shipping the latest code. On July 15, at DebConf25 in Brest, France,
Samuel Henrique walked through the process of providing security
updates to users; he discussed how Debian learns about security
vulnerabilities, decides on the best response, and the process of
sending out updates to keep its users safe. He also provided guidance
on how others could get involved.
The Co-Intelligence Revolution: How Humans and AI Co-Create New Value | Talks at Google
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=Kz1dXcs8zMY
An update on Home Assistant’s Android app
Post Syndicated from jzb original https://lwn.net/Articles/1031129/
The Home Assistant project has published
an update on improvements in its Android app, and plans for upcoming releases:
In our latest update of the Android app 2025.7.1, we’ve added a
couple of useful features. Including a new basic invite flow, which
will be shared between Android and iOS, adding a good layer of
consistency between our most-used companion apps. The idea is to make
it much more seamless to add new users or set up new devices (no need
to type the URL in your Android Automotive device!).We’ve also made My
Links work better. If you’re unfamiliar with My Links, they’re
those cool links (that anyone can
make) that bring you right to an integration, blueprint, add-on,
or settings page. They have always worked great on desktop, but up
until recently, they were a bit clunky to use on mobile. Now you can
get to the link’s destination with a single click.
LWN looked at Home
Assistant in May.
Building Jetflow: a framework for flexible, performant data pipelines at Cloudflare
Post Syndicated from Harry Hough original https://blog.cloudflare.com/building-jetflow-a-framework-for-flexible-performant-data-pipelines-at-cloudflare/
The Cloudflare Business Intelligence team manages a petabyte-scale data lake and ingests thousands of tables every day from many different sources. These include internal databases such as Postgres and ClickHouse, as well as external SaaS applications such as Salesforce. These tasks are often complex and tables may have hundreds of millions or billions of rows of new data each day. They are also business-critical for product decisions, growth plannings, and internal monitoring. In total, about 141 billion rows are ingested every day.
As Cloudflare has grown, the data has become ever larger and more complex. Our existing Extract Load Transform (ELT) solution could no longer meet our technical and business requirements. After evaluating other common ELT solutions, we concluded that their performance generally did not surpass our current system, either.
It became clear that we needed to build our own framework to cope with our unique requirements — and so Jetflow was born.
Over 100x efficiency improvement in GB-s:
-
Our longest running job with 19 billion rows was taking 48 hours using 300 GB of memory, and now completes in 5.5 hours using 4 GB of memory
-
We estimate that ingestion of 50 TB from Postgres via Jetflow could cost under $100 based on rates published by commercial cloud providers
>10x performance improvement:
-
Our largest dataset was ingesting 60-80,000 rows per second, this is now 2-5 million rows per second per database connection.
-
In addition, these numbers scale well with multiple database connections for some databases.
Extensibility:
-
The modular design makes it easy to extend and test. Today Jetflow works with ClickHouse, Postgres, Kafka, many different SaaS APIs, Google BigQuery and many others. It has continued to work well and remain flexible with the addition of new use cases.
The first step to designing our new framework had to be a clear understanding of the problems we were aiming to solve, with clear requirements to stop us creating new ones.
We needed to be able to move more data in less time as some ingestion jobs were taking ~24 hours, and our data will only grow. The data should be ingested in a streaming fashion and use less memory and compute resources than our existing solution.
Given the daily ingestion of thousands of tables, the chosen solution needed to allow for the migration of individual tables as needed. Due to our usage of Spark downstream and Spark’s limitations in merging desperate Parquet schemas, the chosen solution had to offer the flexibility to generate the precise schemas needed for each case to match legacy.
We also required seamless integration with our custom metadata system, used for dependency checks and job status information.
We want a configuration file that can be version-controlled, without introducing bottlenecks on repositories with many concurrent changes.
To increase accessibility for different roles within the team, another requirement was no-code (or configuration as code) in the vast majority of cases. Users should not have to worry about availability or translation of data types between source and target systems, or writing new code for each new ingestion. The configuration needed should also be minimal — for example, data schema should be inferred from the source system and not need to be supplied by the user.
Striking a balance with the no-code requirement above, although we want a low bar of entry we also want to have the option to tune and override options if desired, with a flexible and optional configuration layer. For example, writing Parquet files is often more expensive than reading from the database, so we want to be able to allocate more resources and concurrency as needed.
Additionally, we wanted to allow for control over where the work is executed, with the ability to spin up concurrent workers in different threads, different containers, or on different machines. The execution of workers and communication of data was abstracted away with an interface, and different implementations can be written and injected, controlled via the job configuration.
We wanted a solution capable of running locally in a containerized environment, which would allow us to write tests for every stage of the pipeline. With “black box” solutions, testing often means validating the output after making a change, which is a slow feedback loop, risks not testing all edge cases as there isn’t good visibility of all code paths internally, and makes debugging issues painful.
To build a truly flexible framework, we broke the pipeline down into distinct stages, and then create a config layer to define the composition of the pipeline from these stages, and any configuration overrides. Every pipeline configuration that makes sense logically should execute correctly, and users should not be able to create pipeline configs that do not work.
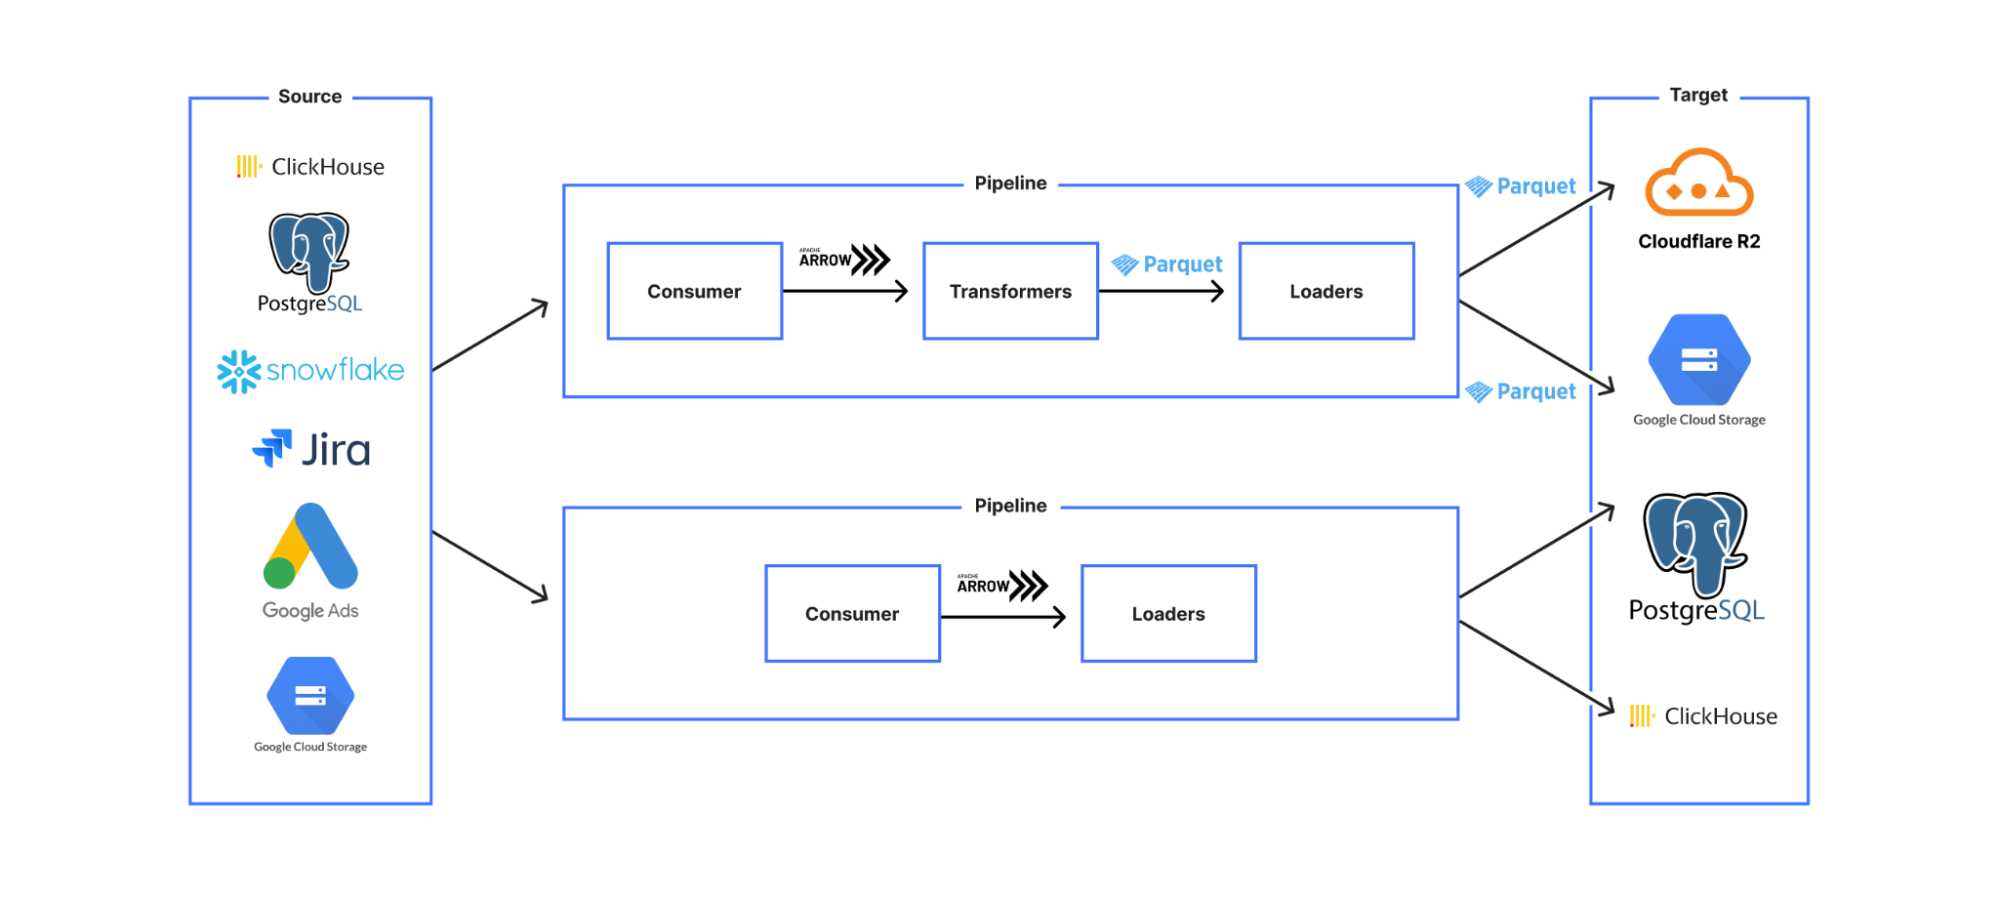
This led us to a design where we created stages which were classified according to the meaningfully different categories of:
-
Consumers
-
Transformers
-
Loaders

The pipeline was constructed via a YAML file that required a consumer, zero or more transformers, and at least one loader. Consumers create a data stream (via reading from the source system), Transformers (e.g. data transformations, validations) take a data stream input and output a data stream conforming to the same API so that they can be chained, and Loaders have the same data streaming interface, but are the stages with persistent effects — i.e. stages where data is saved to an external system.
This modular design means that each stage is independently testable, with shared behaviour (such as error handling and concurrency) inherited from shared base stages, significantly decreasing development time for new use cases and increasing confidence in code correctness.
Next, we designed a breakdown for the data that would allow the pipeline to be idempotent both on whole pipeline re-run and also on internal retry of any data partition due to transient error. We decided on a design that let us parallelize processing, while maintaining meaningful data divisions that allowed the pipeline to perform cleanups of data where required for a retry.
-
RunInstance: the least granular division, corresponding to a business unit for a single run of the pipeline (e.g. one month/day/hour of data).
-
Partition: a division of the RunInstance that allows each row to be allocated to a partition in a way that is deterministic and self-evident from the row data without external state, and is therefore idempotent on retry. (e.g. an accountId range, a 10-minute interval)
-
Batch: a division of the partition data that is non-deterministic and used only to break the data down into smaller chunks for streaming/parallel processing for faster processing with fewer resources. (e.g. 10k rows, 50 MB)
The options that the user configures in the consumer stage YAML both construct the query that is used to retrieve the data from the source system, and also encode the semantic meaning of this data division in a system agnostic way, so that later stages understand what this data represents — e.g. this partition contains the data for all accounts IDs 0-500. This means that we can do targeted data cleanup and avoid, for example, duplicate data entries if a single data partition is retried due to error.

Our most common use case is something like read from a database, convert to Parquet format, and then save to object storage, with each of these steps being a separate stage. As more use cases were onboarded to Jetflow, we had to make sure that if someone wrote a new stage it would be compatible with the other stages. We don’t want to create a situation where new code needs to be written for every output format and target system, or you end up with a custom pipeline for every different use case.
The way we have solved this problem is by having our stage extractor class only allow output data in a single format. This means as long as any downstream stages support this format as in the input and output format they would be compatible with the rest of the pipeline. This seems obvious in retrospect, but internally was a painful learning experience, as we originally created a custom type system and struggled with stage interoperability.
For this internal format, we chose to use Arrow, an in-memory columnar data format. The key benefits of this format for us are:
-
Arrow ecosystem: Many data projects now support Arrow as an output format. This means when we write extractor stages for new data sources, it is often trivial to produce Arrow output.
-
No serialisation overhead: This makes it easy to move Arrow data between machines and even programming languages with minimum overhead. Jetflow was designed from the start to have the flexibility to be able to run in a wide range of systems via a job controller interface, so this efficiency in data transmission means there’s minimal compromise on performance when creating distributed implementations.
-
Reserve memory in large fixed-size batches to avoid memory allocations: As Go is a garbage collected (GC) language and GC cycle times are affected mostly by the number of objects rather than the sizes of those objects, fewer heap objects reduces CPU time spent garbage collecting significantly, even if the total size is the same. As the number of objects to scan, and possibly collect, during a GC cycle increases with the number of allocations, if we have 8192 rows with 10 columns each, Arrow would only require us to do 10 allocations versus the 8192 allocations of most drivers that allocate on a row by row basis, meaning fewer objects and lower GC cycle times with Arrow.
Another important performance optimization was reducing the number of conversion steps that happen when reading and processing data. Most data ingestion frameworks internally represent data as rows. In our case, we are mostly writing data in Parquet format, which is column based. When reading data from column-based sources (e.g. ClickHouse, where most drivers receive RowBinary format), converting into row-based memory representations for the specific language implementation is inefficient. This is then converted again from rows to columns to write Parquet files. These conversions result in a significant performance impact.
Jetflow instead reads data from column-based sources in columnar formats (e.g. for ClickHouse-native Block format) and then copies this data into Arrow column format. Parquet files are then written directly from Arrow columns. The simplification of this process improves performance.
When testing an initial version of Jetflow, we discovered that due to the architecture of ClickHouse, using additional connections would not be of any benefit, since ClickHouse was reading faster than we were receiving data. It should then be possible, with a more optimized database driver, to take better advantage of that single connection to read a much larger number of rows per second, without needing additional connections.
Initially, a custom database driver was written for ClickHouse, but we ended up switching to the excellent ch-go low level library, which directly reads Blocks from ClickHouse in a columnar format. This had a dramatic effect on performance in comparison to the standard Go driver. Combined with the framework optimisations above, we now ingest millions of rows per second with a single ClickHouse connection.
A valuable lesson learned is that as with any software, tradeoffs are often made for the sake of convenience or a common use case that may not match your own. Most database drivers tend not to be optimized for reading large batches of rows, and have high per-row overhead.
For Postgres, we use the excellent jackc/pgx driver, but instead of using the database/sql Scan interface, we directly receive the raw bytes for each row and use the jackc/pgx internal scan functions for each Postgres OID (Object Identifier) type.
The database/sql Scan interface in Go uses reflection to understand the type passed to the function and then also uses reflection to set each field with the column value received from Postgres. In typical scenarios, this is fast enough and easy to use, but falls short for our use cases in terms of performance. The jackc/pgx driver reuses the row bytes produced each time the next Postgres row is requested, resulting in zero allocations per row. This allows us to write high-performance, low-allocation code within Jetflow. With this design, we are able to achieve nearly 600,000 rows per second per Postgres connection for most tables, with very low memory usage.
As of early July 2025, the team ingests 77 billion records per day via Jetflow. The remaining jobs are in the process of being migrated to Jetflow, which will bring the total daily ingestion to 141 billion records. The framework has allowed us to ingest tables in cases that would not otherwise have been possible, and provided significant cost savings due to ingestions running for less time and with fewer resources.
In the future, we plan to open source the project, and if you are interested in joining our team to help develop tools like this, then open roles can be found at https://www.cloudflare.com/careers/jobs/.
Prokop: What to expect from Debian/trixie
Post Syndicated from corbet original https://lwn.net/Articles/1031106/
Michael Prokop has posted a
lengthy list of changes coming in the Debian “trixie” release, due in
early August. “As usual with major upgrades, there are some things to
“
be aware of, and hereby I’m starting my public notes on trixie that might
be worth for other folks. My focus is primarily on server systems and
looking at things from a sysadmin perspective.
[$] Deep immutability for Python
Post Syndicated from daroc original https://lwn.net/Articles/1030291/
Python has recently seen a number of experiments to improve its parallel
performance, including exposing
subinterpreters as part of the standard library. These allow
separate threads within the same Python process to run simultaneously, as long
as any data sent between them is copied, rather than shared.
PEP 795 (“Deep Immutability in Python”)
seeks to make efficient sharing of data between subinterpreters possible by
allowing Python objects to be “frozen”, so that they can be accessed from
multiple subinterpreters without copying or synchronization.
That task is more difficult than it
seems, and the PEP prompted a good deal of skepticism from the Python community.
Security updates for Wednesday
Post Syndicated from jzb original https://lwn.net/Articles/1031104/
Security updates have been issued by AlmaLinux (cloud-init, fence-agents, git, kernel, and kernel-rt), Debian (openjdk-11), Fedora (firefox, golang, libinput, transfig, and yasm), Mageia (qtbase5, qtbase6), Red Hat (fence-agents, go-toolset:rhel8, golang, kernel, and python-setuptools), Slackware (mozilla), SUSE (cyradm, gstreamer-plugins-base, and xen), and Ubuntu (gdk-pixbuf, jq, linux-gcp, linux-gcp-6.8, linux-oracle, ruby-sinatra, thunderbird, and unbound).
Tinian: The Forgotten Invasion
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=l7bzVtShyjs
Ritchie Torres and the Fight for the Political Center | The David Frum Show
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=0kISxha7bJA
Google Sues the Badbox Botnet Operators
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/07/google-sues-the-badbox-botnet-operators.html
It will be interesting to watch what will come of this private lawsuit:
Google on Thursday announced filing a lawsuit against the operators of the Badbox 2.0 botnet, which has ensnared more than 10 million devices running Android open source software.
These devices lack Google’s security protections, and the perpetrators pre-installed the Badbox 2.0 malware on them, to create a backdoor and abuse them for large-scale fraud and other illicit schemes.
This reminds me of Meta’s lawauit against Pegasus over its hack-for-hire software (which I wrote about here.) It’s a private company stepping into a regulatory void left by governments.
Slashdot thread.
Creating a space for connection and code: Meet Seung Woo (Tony), Canada
Post Syndicated from Sophie Ashford original https://www.raspberrypi.org/blog/creating-a-space-for-connection-and-code-meet-seung-woo-tony-canada/
We love hearing from members of the community and sharing the stories of amazing young people, volunteers, and educators who are using their passion for technology to create positive change in the world around them.
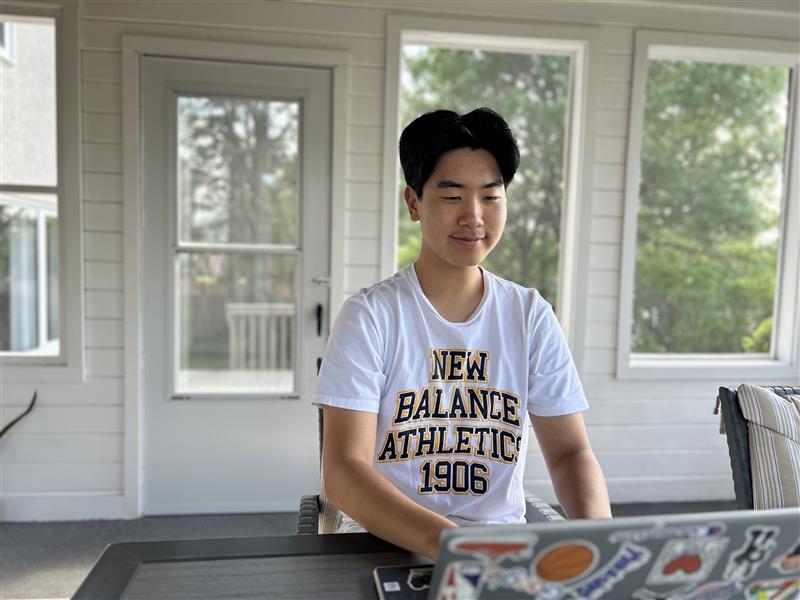
Seung Woo, also known as Tony, is a 17-year-old student from Canada and the co-founder of his school’s Code Club, alongside his teacher, Kay. A curious and driven teen with big ambitions in computer science, Tony is not only passionate about technology, but also dedicated to building a safe, welcoming space where others can learn, explore, and grow alongside him.
A spark of inspiration
Tony’s fascination with computers started early, driven by his love of video games, coding, and, perhaps most memorably, his admiration for Tony Stark, the comic-book and film character who becomes the superhero Iron Man! The idea of building something powerful from scratch stuck with him.
“My whole life, I have been curious about the inner workings of a computer and my inspiration for coding is Tony Stark or Iron Man from the Marvel Cinematic Universe!”
Tony’s early coding journey wasn’t without its challenges. Finding the right resources was difficult, and staying motivated during tough moments was often hard without a support system.
“Like many others, I was independently taught, and during this time of independent learning I’d find many different roadblocks and challenges that I had to overcome alone. A big setback for me was finding the right resources in order to learn how to code. Another big obstacle for me was motivation. I would find myself losing interest in a project. I didn’t have the exterior motivation to help me push through the inevitable hardships that come with coding.”
That’s where the idea for a coding club began to take shape.
Creating a community of coders
Tony co-founded the Code Club at Collège Jeanne-Sauvé in December 2024 with that exact vision in mind — he wanted to provide a fun, collaborative, and welcoming environment where students of all skill levels could explore their love of technology together.
“I created the coding club to help everyone on their journey of computer science, no matter their skill level, and that is exactly what it is turning out to be. Finding resources is easier than ever with a teacher and all of the amazing members.”
Tony’s teacher and co-founder, Kay, shared why Code Club was the right fit for the school.
“I thought Code Club was the best way to start our club for a few reasons. The amount of coding language options was varied and appealed to the different learners in our club. It was also important for us to promote our club and let our community know about the presence of a coding club in our school, and Code Club helped us do so via their online presence.”
What makes Code Club special
For Tony, the secret ingredient behind his club’s success is simple: teamwork.
“Without teamwork, our club wouldn’t really be a club, it would simply be an ensemble of people coding in their own little cubicles, much like a stereotypical office job, and to me, that does not sound too enjoyable. Teamwork is our little secret ingredient in problem-solving and building motivation, we embrace it by creating a safe space where everyone can speak their minds without judgement!”
Members are free to choose their own learning paths. No matter the project, the atmosphere is always filled with laughter, energy, and curiosity.
“Coding should be something that is fun — not stressful like others may make it seem. Celebrating achievements, making short term goals, and problem solving with friends are all great ways that we make coding fun in our club. A second word would be teamwork. Without teamwork, our club wouldn’t really be a club.”
Teamwork, he adds, transforms what could be a solitary activity into something social and deeply motivating.
Looking to the future
Tony hopes the club will continue to grow, bringing more students into the world of coding and helping them feel at home in it. His story is a great reminder that learning to code isn’t just about computers — it’s about building community, confidence, and creativity.
“I wanted to create a space where everyone would be accepted and encouraged to learn more about coding and not be ashamed to ‘nerd out’ about this subject like I do very frequently. I’ve dreamed of creating a space that embraces this beautiful passion.”
If you’d like to explore coding, you can get started at home with over 250 free projects.
For a little more support, or if you’re open to mentoring others, you can also join a Code Club. Check our website to find a club near you and become part of a like-minded and welcoming community.
The post Creating a space for connection and code: Meet Seung Woo (Tony), Canada appeared first on Raspberry Pi Foundation.
Comic for 2025.07.23 – Linus
Post Syndicated from Explosm.net original https://explosm.net/comics/linus
New Cyanide and Happiness Comic
Single Strike Sadly Slays Several Sheep
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/F4JlrSTj5zU
Flettner Rotor
Post Syndicated from xkcd.com original https://xkcd.com/3119/