Introducing pay per crawl: enabling content owners to charge AI crawlers for access

Post Syndicated from Will Allen original https://blog.cloudflare.com/introducing-pay-per-crawl/

A changing landscape of consumption 

Many publishers, content creators and website owners currently feel like they have a binary choice — either leave the front door wide open for AI to consume everything they create, or create their own walled garden. But what if there was another way?

At Cloudflare, we started from a simple principle: we wanted content creators to have control over who accesses their work. If a creator wants to block all AI crawlers from their content, they should be able to do so. If a creator wants to allow some or all AI crawlers full access to their content for free, they should be able to do that, too. Creators should be in the driver’s seat.

After hundreds of conversations with news organizations, publishers, and large-scale social media platforms, we heard a consistent desire for a third path: They’d like to allow AI crawlers to access their content, but they’d like to get compensated. Currently, that requires knowing the right individual and striking a one-off deal, which is an insurmountable challenge if you don’t have scale and leverage. 

What if I could charge a crawler? 

We believe your choice need not be binary — there should be a third, more nuanced option: You can charge for access. Instead of a blanket block or uncompensated open access, we want to empower content owners to monetize their content at Internet scale.

We’re excited to help dust off a mostly forgotten piece of the web: HTTP response code 402.

Introducing pay per crawl

Pay per crawl, in private beta, is our first experiment in this area. 

Pay per crawl integrates with existing web infrastructure, leveraging HTTP status codes and established authentication mechanisms to create a framework for paid content access. 

Each time an AI crawler requests content, they either present payment intent via request headers for successful access (HTTP response code 200), or receive a 402 Payment Required response with pricing. Cloudflare acts as the Merchant of Record for pay per crawl and also provides the underlying technical infrastructure.

Publisher controls and pricing

Pay per crawl grants domain owners full control over their monetization strategy. They can define a flat, per-request price across their entire site. Publishers will then have three distinct options for a crawler:

  • Allow: Grant the crawler free access to content.

  • Charge: Require payment at the configured, domain-wide price.

  • Block: Deny access entirely, with no option to pay.
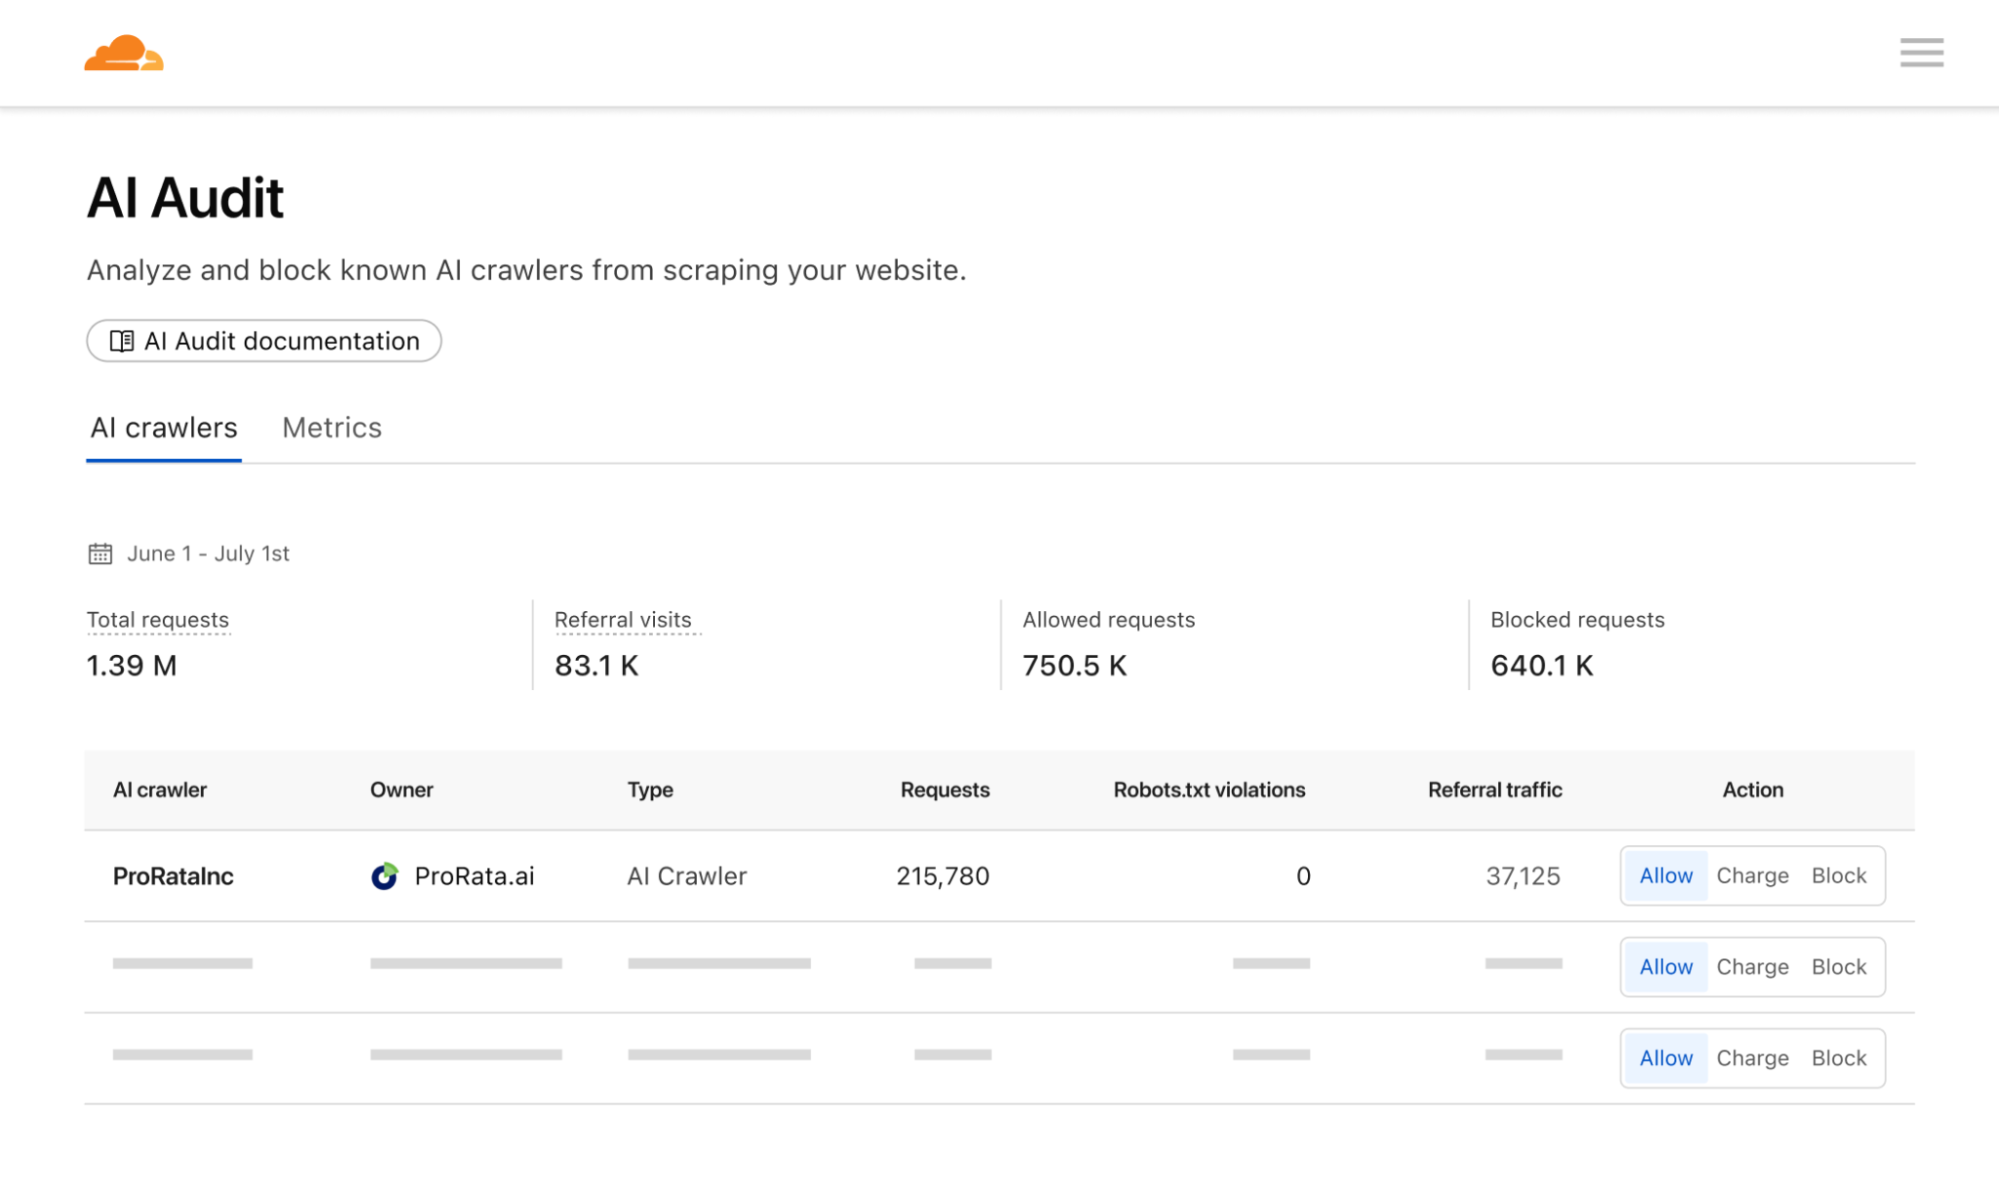

An important mechanism here is that even if a crawler doesn’t have a billing relationship with Cloudflare, and thus couldn’t be charged for access, a publisher can still choose to ‘charge’ them. This is the functional equivalent of a network level block (an HTTP 403 Forbidden response where no content is returned) — but with the added benefit of telling the crawler there could be a relationship in the future. 

While publishers currently can define a flat price across their entire site, they retain the flexibility to bypass charges for specific crawlers as needed. This is particularly helpful if you want to allow a certain crawler through for free, or if you want to negotiate and execute a content partnership outside the pay per crawl feature. 

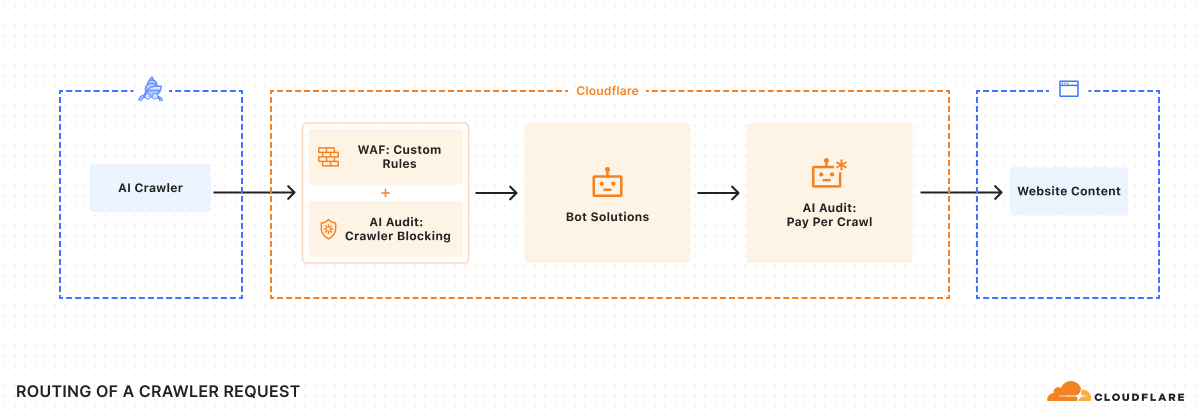
To ensure integration with each publisher’s existing security posture, Cloudflare enforces Allow or Charge decisions via a rules engine that operates only after existing WAF policies and bot management or bot blocking features have been applied.

Payment headers and access

As we were building the system, we knew we had to solve an incredibly important technical challenge: ensuring we could charge a specific crawler, but prevent anyone from spoofing that crawler. Thankfully, there’s a way to do this using Web Bot Auth proposals.

For crawlers, this involves:

  • Generating an Ed25519 key pair, and making the JWK-formatted public key available in a hosted directory

  • Registering with Cloudflare to provide the URL of your key directory and user agent information.

  • Configuring your crawler to use HTTP Message Signatures with each request.

Once registration is accepted, crawler requests should always include signature-agent, signature-input, and signature headers to identify your crawler and discover paid resources.

GET /example.html
Signature-Agent: "https://signature-agent.example.com"
Signature-Input: sig2=("@authority" "signature-agent")
 ;created=1735689600
 ;keyid="poqkLGiymh_W0uP6PZFw-dvez3QJT5SolqXBCW38r0U"
 ;alg="ed25519"
 ;expires=1735693200
;nonce="e8N7S2MFd/qrd6T2R3tdfAuuANngKI7LFtKYI/vowzk4lAZYadIX6wW25MwG7DCT9RUKAJ0qVkU0mEeLElW1qg=="
 ;tag="web-bot-auth"
Signature: sig2=:jdq0SqOwHdyHr9+r5jw3iYZH6aNGKijYp/EstF4RQTQdi5N5YYKrD+mCT1HA1nZDsi6nJKuHxUi/5Syp3rLWBA==:

Accessing paid content

Once a crawler is set up, determination of whether content requires payment can happen via two flows:

Reactive (discovery-first)

Should a crawler request a paid URL, Cloudflare returns an HTTP 402 Payment Required response, accompanied by a crawler-price header. This signals that payment is required for the requested resource.

HTTP 402 Payment Required
crawler-price: USD XX.XX

 The crawler can then decide to retry the request, this time including a crawler-exact-price header to indicate agreement to pay the configured price.

GET /example.html
crawler-exact-price: USD XX.XX 

Proactive (intent-first)

Alternatively, a crawler can preemptively include a crawler-max-price header in its initial request.

GET /example.html
crawler-max-price: USD XX.XX

If the price configured for a resource is equal to or below this specified limit, the request proceeds, and the content is served with a successful HTTP 200 OK response, confirming the charge:

HTTP 200 OK
crawler-charged: USD XX.XX 
server: cloudflare

If the amount in a crawler-max-price request is greater than the content owner’s configured price, only the configured price is charged. However, if the resource’s configured price exceeds the maximum price offered by the crawler, an HTTP 402 Payment Required response is returned, indicating the specified cost.  Only a single price declaration header, crawler-exact-price or crawler-max-price, may be used per request.

The crawler-exact-price or crawler-max-price headers explicitly declare the crawler’s willingness to pay. If all checks pass, the content is served, and the crawl event is logged. If any aspect of the request is invalid, the edge returns an HTTP 402 Payment Required response.

Financial settlement

Crawler operators and content owners must configure pay per crawl payment details in their Cloudflare account. Billing events are recorded each time a crawler makes an authenticated request with payment intent and receives an HTTP 200-level response with a crawler-charged header. Cloudflare then aggregates all the events, charges the crawler, and distributes the earnings to the publisher.

Content for crawlers today, agents tomorrow 

At its core, pay per crawl begins a technical shift in how content is controlled online. By providing creators with a robust, programmatic mechanism for valuing and controlling their digital assets, we empower them to continue creating the rich, diverse content that makes the Internet invaluable. 

We expect pay per crawl to evolve significantly. It’s very early: we believe many different types of interactions and marketplaces can and should develop simultaneously. We are excited to support these various efforts and open standards.

For example, a publisher or new organization might want to charge different rates for different paths or content types. How do you introduce dynamic pricing based not only upon demand, but also how many users your AI application has? How do you introduce granular licenses at internet scale, whether for training, inference, search, or something entirely new?

The true potential of pay per crawl may emerge in an agentic world. What if an agentic paywall could operate entirely programmatically? Imagine asking your favorite deep research program to help you synthesize the latest cancer research or a legal brief, or just help you find the best restaurant in Soho — and then giving that agent a budget to spend to acquire the best and most relevant content. By anchoring our first solution on HTTP response code 402, we enable a future where intelligent agents can programmatically negotiate access to digital resources. 

Getting started

Pay per crawl is currently in private beta. We’d love to hear from you if you’re either a crawler interested in paying to access content or a content creator interested in charging for access. You can reach out to us at http://www.cloudflare.com/paypercrawl-signup/ or contact your Account Executive if you’re an existing Enterprise customer.
From Googlebot to GPTBot: who’s crawling your site in 2025

Post Syndicated from João Tomé original https://blog.cloudflare.com/from-googlebot-to-gptbot-whos-crawling-your-site-in-2025/

Web crawlers are not new. The World Wide Web Wanderer debuted in 1993, though the first web search engines to truly use crawlers and indexers were JumpStation and WebCrawler. Crawlers are part of one of the backbones of the Internet’s success: search. Their main purpose has been to index the content of websites across the Internet so that those websites can appear in search engine results and direct users appropriately. In this blog post, we’re analyzing recent trends in web crawling, which now has a crucial and complex new role with the rise of AI.

Not all crawlers are the same. Bots, automated scripts that perform tasks across the Internet, come in many forms: those considered non-threatening or “good” (such as API clients, search indexing bots like Googlebot, or health checkers) and those considered malicious or “bad” (like those used for credential stuffing, spam, or scraping content without permission). In fact, around 30% of global web traffic today, according to Cloudflare Radar data, comes from bots, and even exceeds human Internet traffic in some locations.

A new category, AI crawlers, has emerged in recent years. These bots collect data from across the web to train AI models, improving tools and experiences, but also raising issues around content rights, unauthorized use, and infrastructure overload. We aimed to confirm the growth of both search and AI crawlers, examine specific AI crawlers, and understand broader crawler usage.

This is increasingly relevant with the rapid adoption of AI, growing content rights concerns, and data privacy discussions. Some sites and creators are looking to limit or block AI crawlers using tools like robots.txt or firewall rules. Others, like Dutch indie maker and entrepreneur Pieter Levels, have embraced them: “I’m 100% fine with AI crawlers… very important to rank in LLMs [large language models]”.

It’s important to note that crawlers serve different purposes. For example, the facebookexternalhit bot is not included in this analysis, as it is used by Facebook to fetch page content when generating previews for shared links. However, within this post, we are only focusing on AI and search crawlers that are indexing or scraping website content.

AI-only crawlers perspective

Let’s start with an AI-only crawler perspective that we currently have on Cloudflare Radar, focused only on crawlers advertised as AI-related. To identify them, we’re using here a list derived from an open-source project that helps website owners manage and control access to AI crawlers — especially those used to train large language models (LLMs). It also provides guidance on what to include in robots.txt files (more on that below). The data shown below is based on matching those crawler names with user-agent strings in HTTP requests. (Further details, including one exception, about this method can be found at the end of the blog post.)

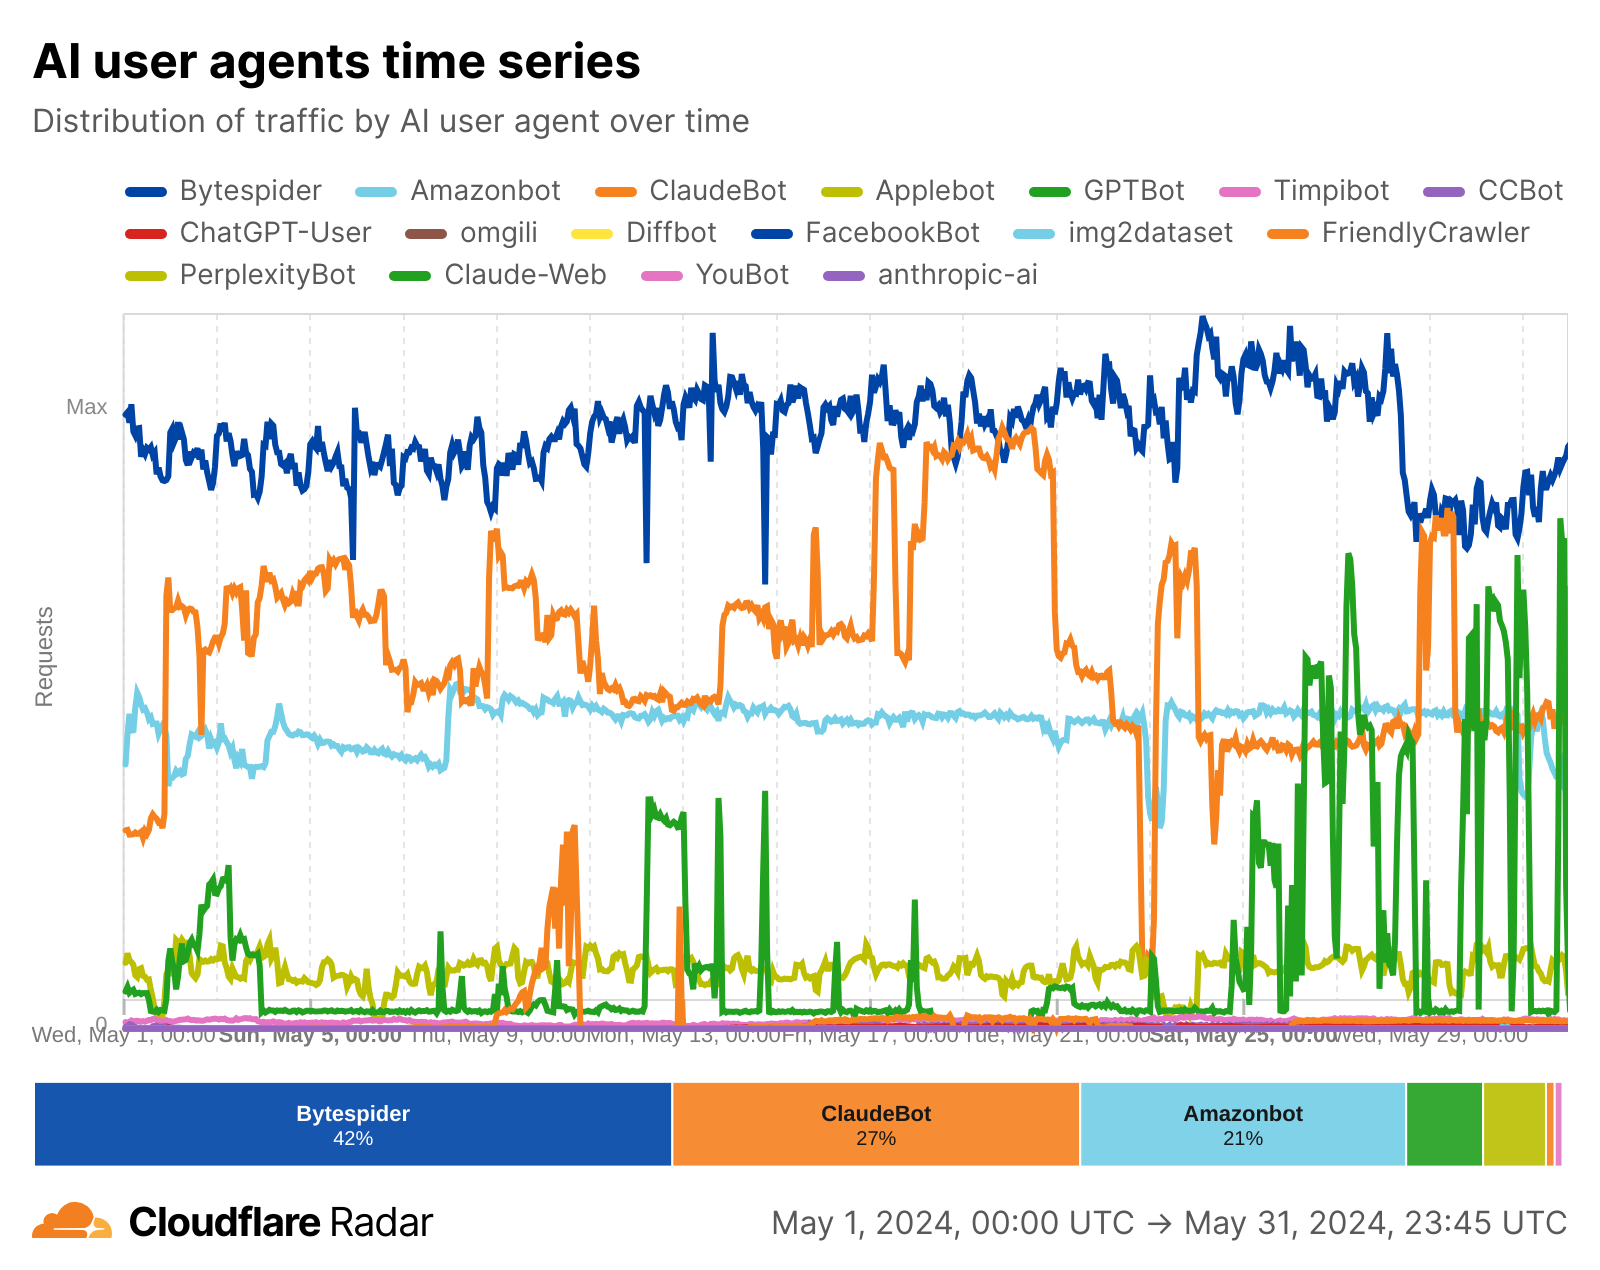
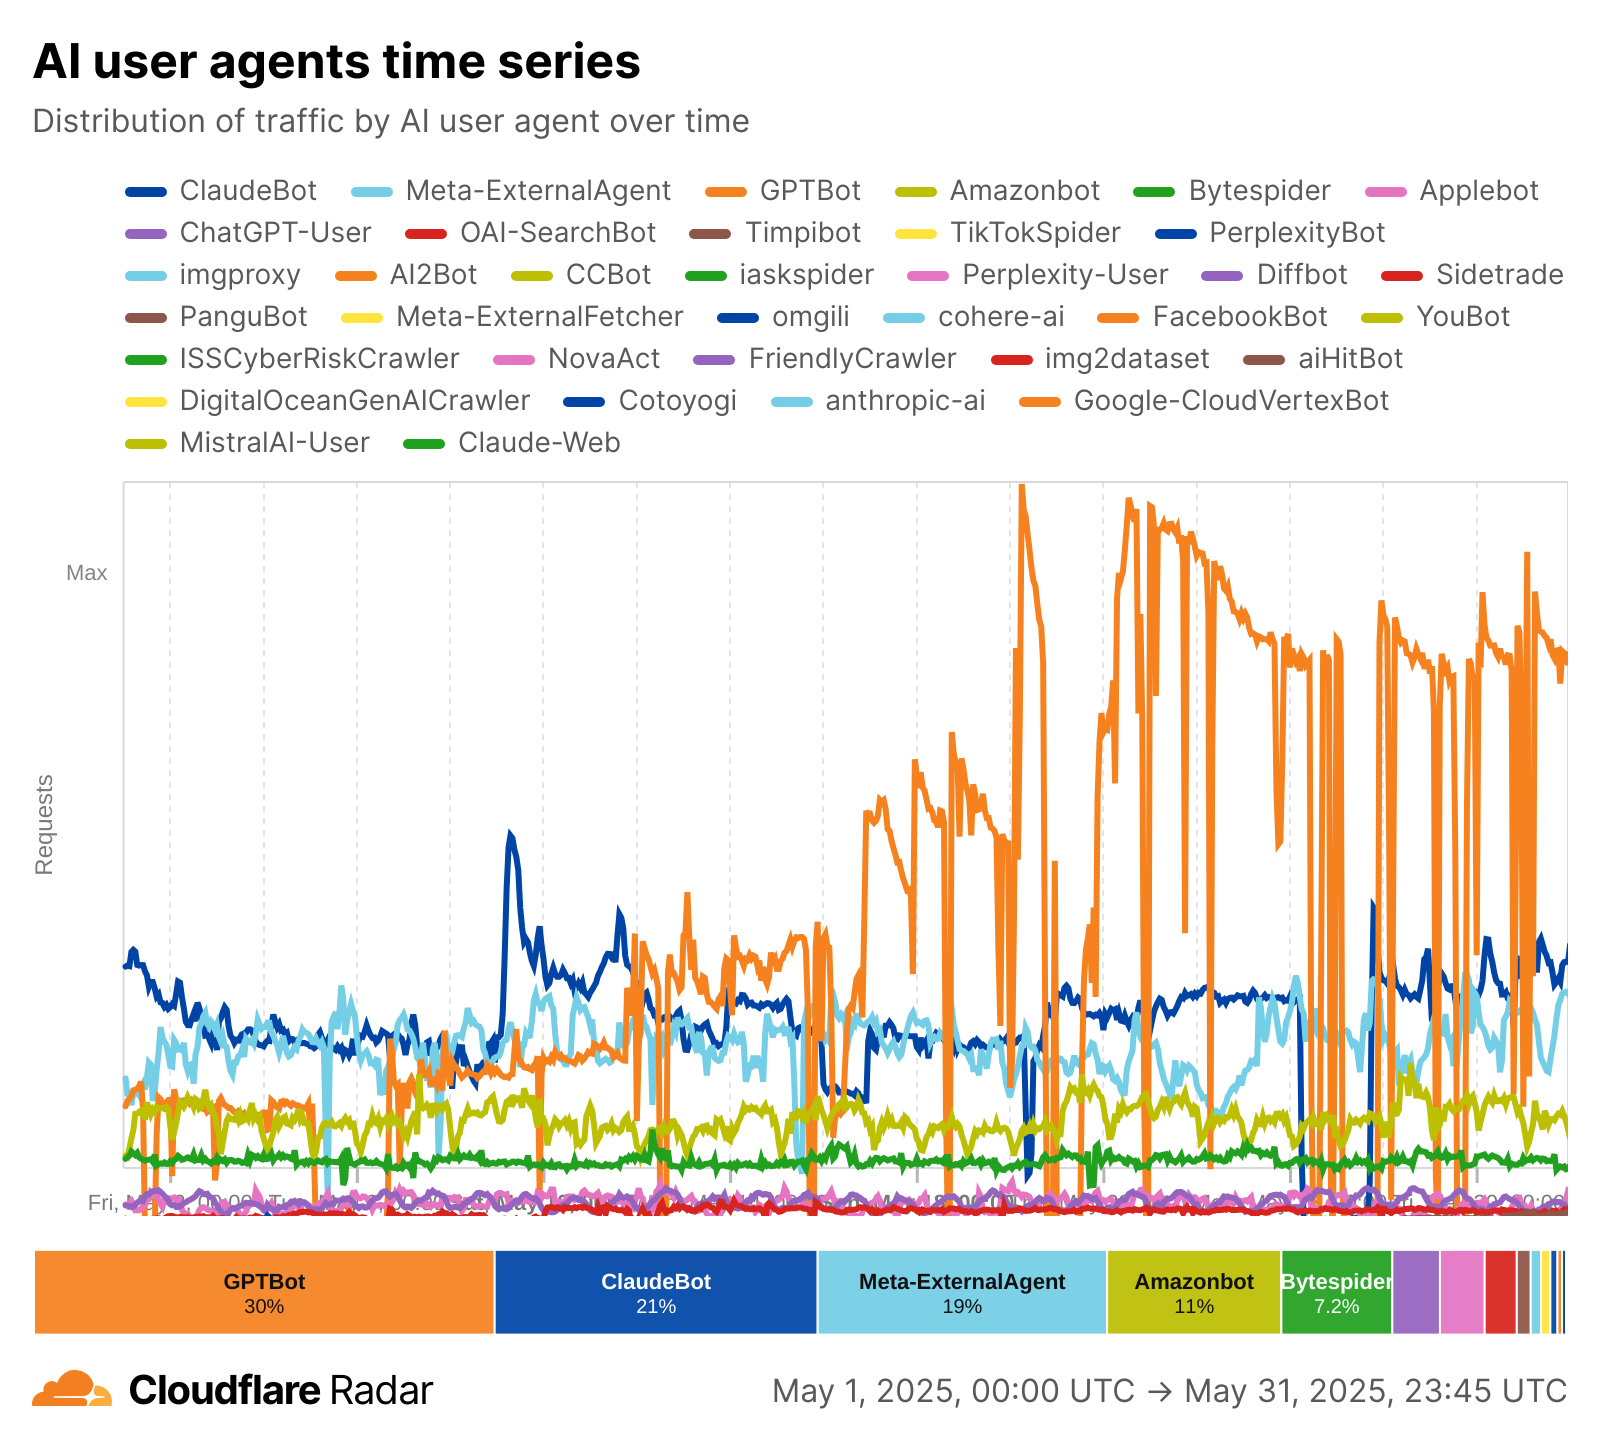
The AI crawler landscape saw a significant shift between May 2024 and May 2025, with GPTBot (from OpenAI) emerging as the dominant force, surging from 5% to 30% share, and Meta-ExternalAgent (from Meta) making a strong new entry at 19%. This growth came at the expense of former leader Bytespider, which plummeted from 42% to 7%, as well as other AI crawlers like ClaudeBot and Amazonbot, which also saw declines. Our data clearly indicates a reordering of top AI crawlers, highlighting the increasing prominence of OpenAI and Meta in this category.

May 2024


May 2025


Rank

Bot Name

Share (May 2024)

Rank

Bot Name

Share (May 2025)

1

Bytespider

42%

1

GPTBot

30%

2

ClaudeBot

27%

2

ClaudeBot

21%

3

Amazonbot

21%

3

Meta-ExternalAgent

19%

4

GPTBot

5%

4

Amazonbot

11%

5

Applebot

4.1%

5

Bytespider

7.2%

Rank Bot Name Share (May 2024) Rank Bot Name Share (May 2025)
1 Bytespider 42% 1 GPTBot 30%
2 ClaudeBot 27% 2 ClaudeBot 21%
3 Amazonbot 21% 3 Meta-ExternalAgent 19%
4 GPTBot 5% 4 Amazonbot 11%
5 Applebot 4.1% 5 Bytespider 7.2%

For additional context, the list below includes further information about the bots with higher crawling shares seen above. This information comes from the same open-source list mentioned above and from publications by companies like OpenAI, which explain how their crawlers are used. 

  • GPTBot – OpenAI’s crawler used to improve and train large language models like ChatGPT.

  • ClaudeBot – Anthropic’s crawler for training and updating the Claude AI assistant.

  • Meta-ExternalAgent – Meta’s bot likely used for collecting data to train or fine-tune LLMs.

  • Amazonbot – Amazon’s crawler that gathers data for its search and AI applications.

  • Bytespider – ByteDance’s AI data collector, often linked to training models like Ernie or TikTok-related AI.

  • Applebot – Apple’s web crawler primarily for Siri and Spotlight search, possibly used in AI development.

  • OAI-SearchBot – OpenAI’s search-focused crawler, likely used for retrieving real-time web info for models.

  • ChatGPT-User – Represents API-based or browser usage of ChatGPT in connection with user interactions.

  • PerplexityBot – Crawler from Perplexity.ai, which powers their AI answer engine using real-time web data.

Webmasters can inform crawler operators of whether they want these bots and crawlers to access their content by setting out rules in a file called robots.txt, which tells crawlers what pages they should or shouldn’t access. As we’ve seen recently, crawlers honoring your robots.txt policies is voluntary, but Cloudflare announced tools like AI Audit to help content creators to enforce it.

Now, as we’ve seen, the landscape of web crawling is evolving rapidly, driven by the merging roles of search engines and AI. AI is now deeply integrated into search, seen in Google’s AI Overviews and AI Mode, but also in social media platforms, like Meta AI on Instagram. So, let’s broaden our analysis to include these wider AI-driven crawling activities.

General AI and search crawling growth: +18%

A broader view reveals the growth of crawling traffic from both search and AI crawlers over the first few months of 2025. To remove customer growth bias, we’ll analyze trends using a fixed set of customers from specific weeks (a method we’ve used in our Cloudflare Radar Year in Review): the first week of May 2024, a week in November 2024, and the first week of April 2025. 

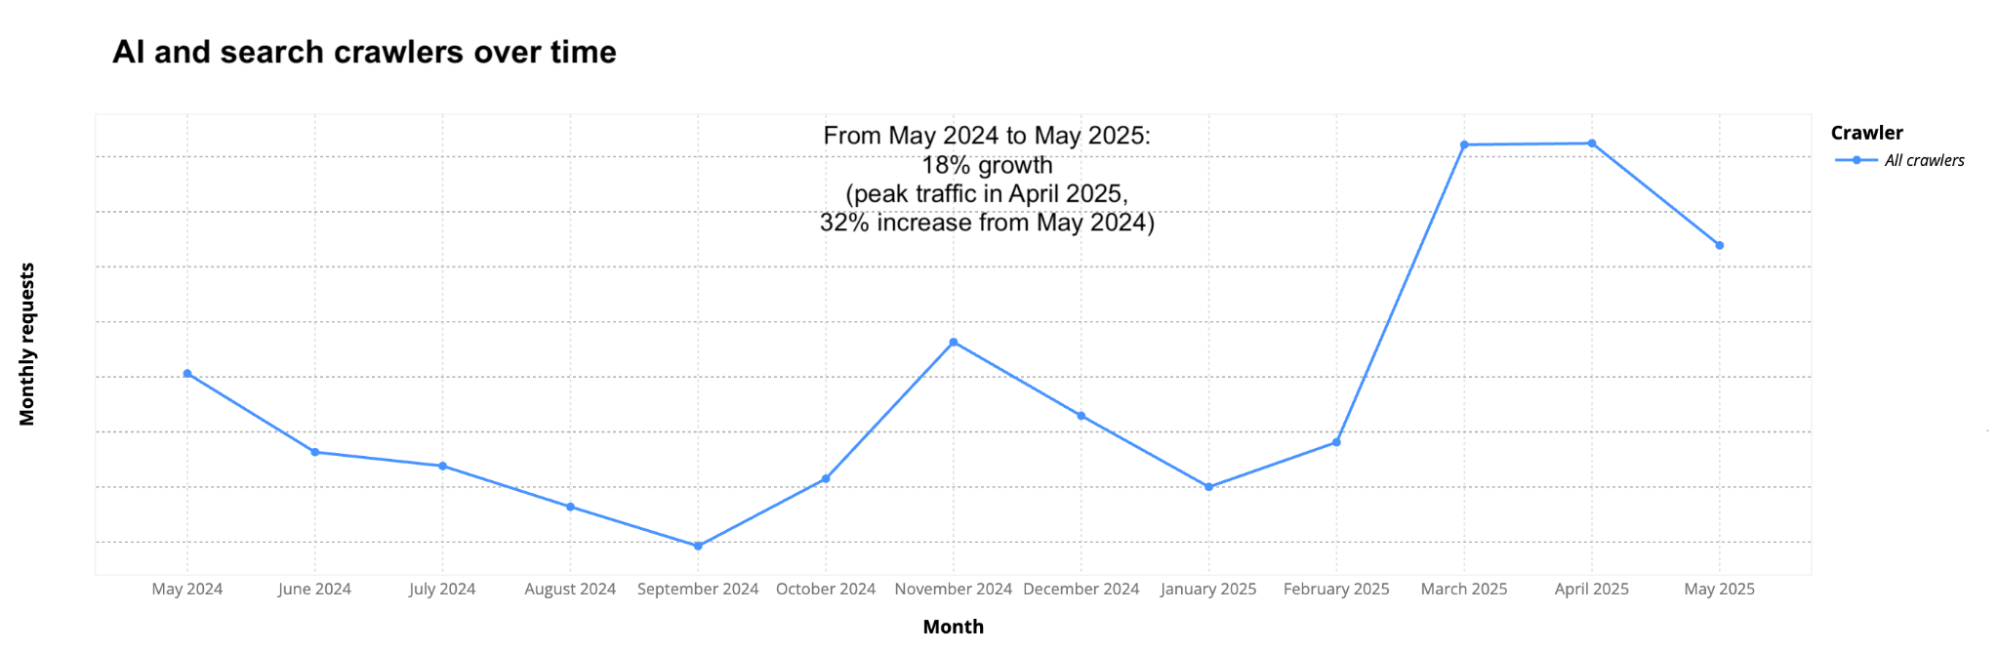
Using that method, we found that AI and search crawler traffic grew by 18% from May 2024 to May 2025 (comparing full-month periods). The increase was even higher, at 48%, when including new Cloudflare customers added during that time. Peak AI and search crawling traffic occurred in April 2025, with a 32% increase compared to May 2024. This confirms that crawling traffic has clearly risen over the past year, but also that growth is not always constant. Google remains the dominant player, and its share is growing too, as we’ll see in the next section.

As the next chart shows, crawling traffic increased sharply in March and April 2025 and remained high, though slightly lower, in May.


The patterns on the above crawling chart also seem to reflect broader seasonal patterns and general human Internet traffic patterns. In 2024, traffic dropped during the summer in the Northern Hemisphere, with August and September being the least active months. And like overall Internet traffic, it then rose in November, when people are typically more online due to shopping and seasonal habits, as we’ve seen in past analyses. 

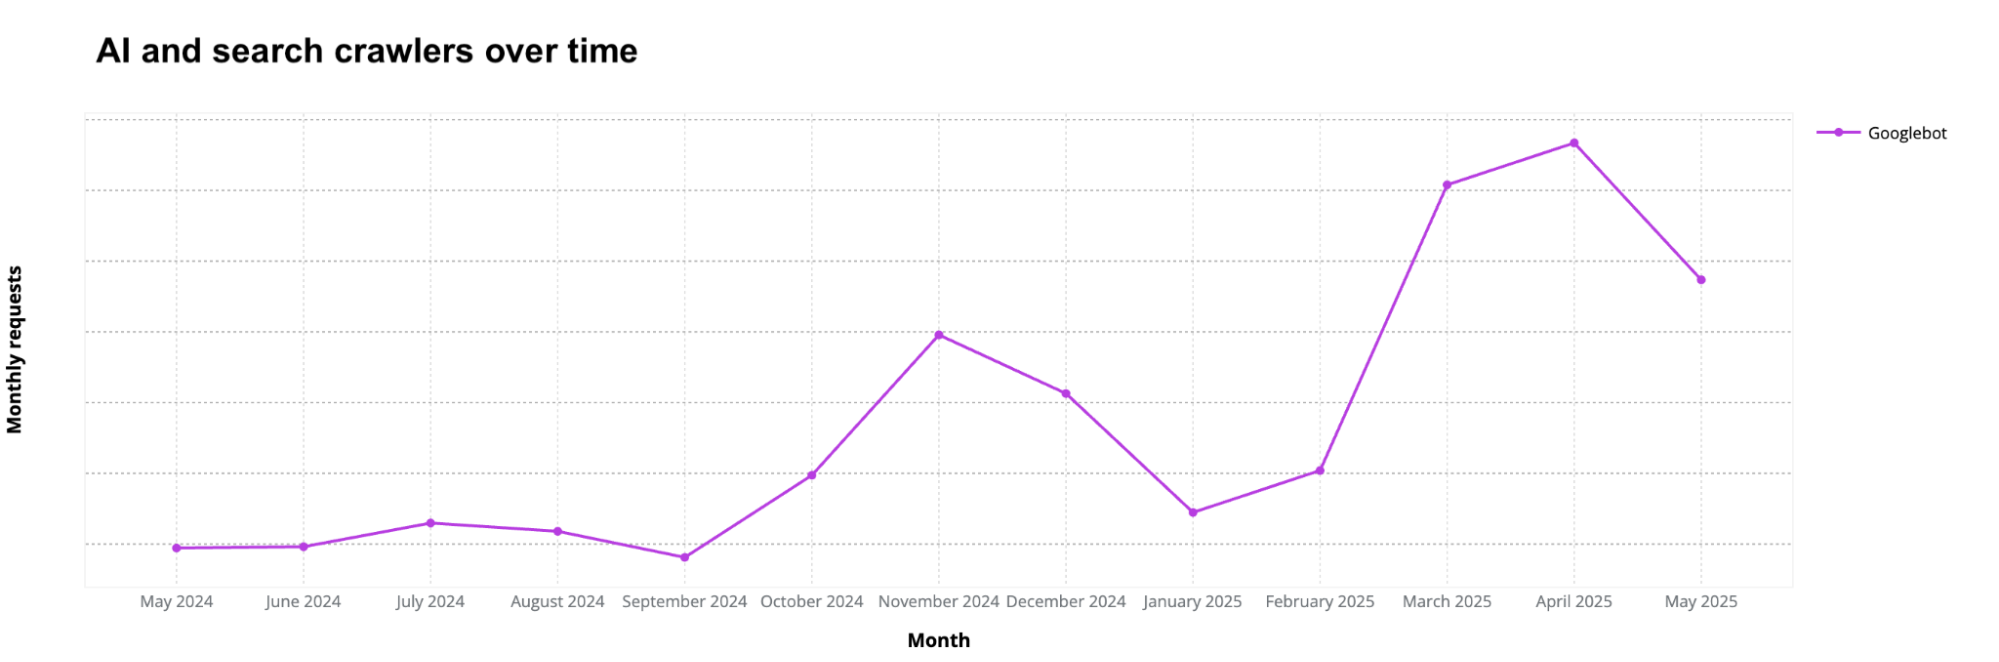
Googlebot crawling grew 96% in one year

Googlebot, which indexes content for Google Search, was clearly the top crawler throughout the period and showed strong growth, up 96% from May 2024 to May 2025, reflecting increased crawling by Google. Crawling traffic peaked in April 2025, reaching 145% higher than in May 2024. It’s also important to mention that Google made changes to its search and launched AI Overviews in its search engine during this time — first in the US in May 2024, then in more countries later.


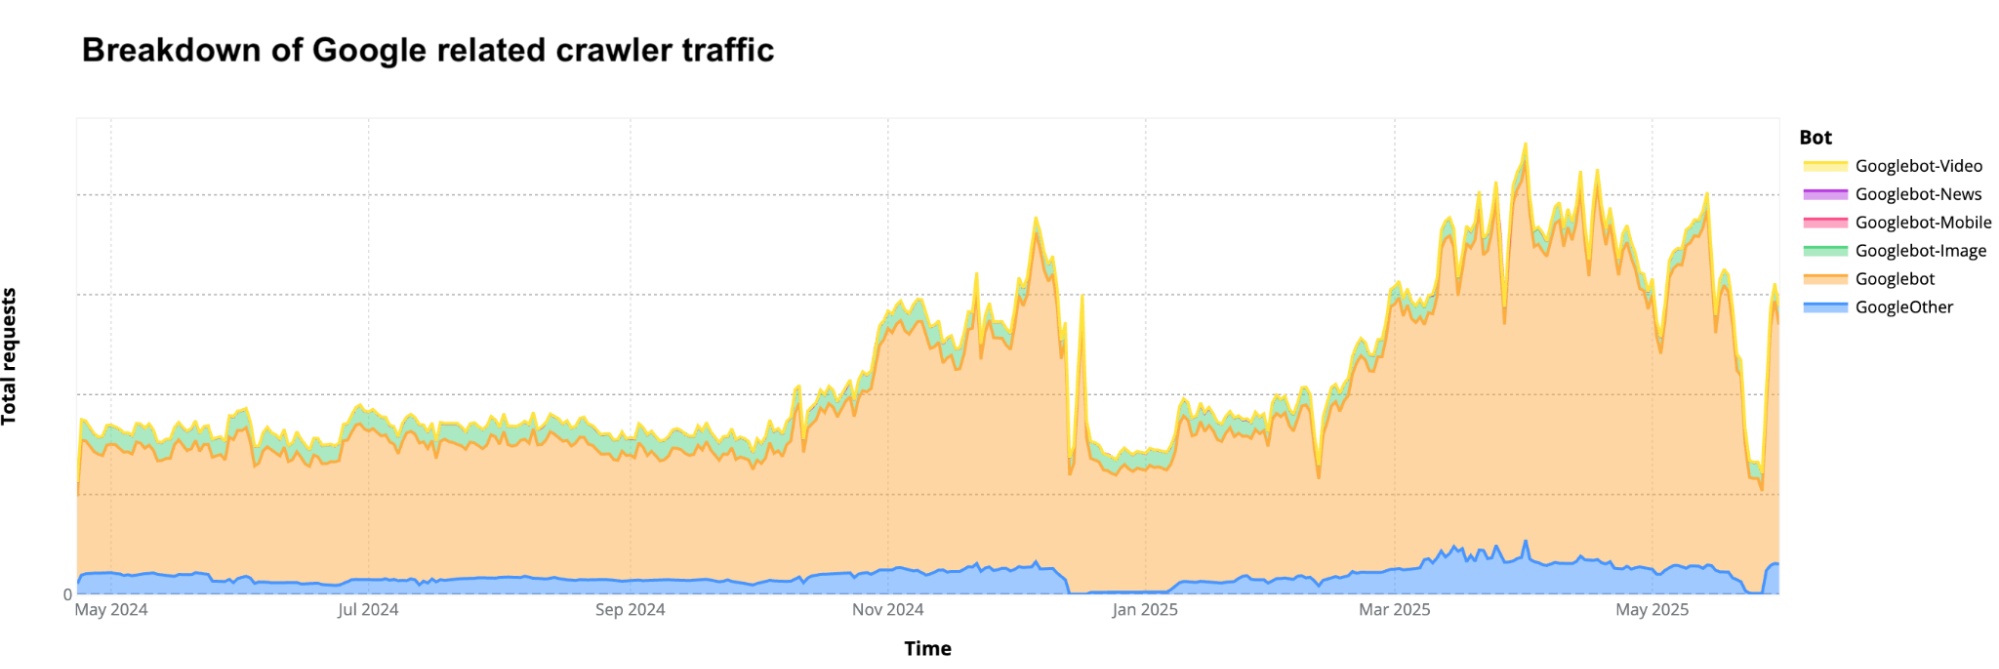
Two trends stand out when looking at daily data for Google-related crawlers, as shown in the graph below. First, Googlebot and the more recent GoogleOther (a web crawler from 2023 for “research and development”) account for most of Google’s crawling activity. Second, there were two visible drops in crawling traffic: one on December 14, 2024 (around a Google Search update), and another from May 20 to May 28, 2025. That May 20 drop occurred around the same time as the rollout of AI Mode on Google Search in the US, although the timing may be coincidental.


Breakdown of top 20 AI and search web crawlers 

Ranking crawlers by their share of total requests gives a clearer picture of which bots are gaining or losing ground, especially among those focused on search and AI. The table below shows a clear trend: some AI bots have grown rapidly since last year (with growth beginning even earlier), while many traditional search crawlers have remained flat or lost share (as in the case of Bing and its Bingbot crawler). The main exception is Googlebot.

The next table shows the percentage share of each crawler out of all crawling traffic generated by this specific cohort of over 30 AI & search crawlers observed by Cloudflare in May 2024 and May 2025. The table below also includes the change in percentage points and the growth or decline in raw request volume. Crawlers are ranked by their share in May 2025. Key crawler shifts include GPTBot rising sharply (+305%), while Bytespider dropped dramatically (-85%).

Rank

Bot name

Share
May 2024

Share
May 2025

Δ percentage-point change

Raw requests growth (May 2024 to May 2025)

1

Googlebot

30%

50%

+20 pp

96%

2

Bingbot

10%

8.7%

-1.3 pp

2%

3

GPTBot

2.2%

7.7%

+5.5 pp

305%

4

ClaudeBot

11.7%

5.4%

-6.3 pp

-46%

5

GoogleOther

4.4%

4.3%

-0.1 pp

14%

6

Amazonbot

7.6%

4.2%

-3.4 pp

-35%

7

Googlebot-Image

4.5%

3.3%

-1.2 pp

-13%

8

Bytespider

22.8%

2.9%

-19.8 pp

-85%

9

Yandex

2.8%

2.2%

-0.7 pp

-10%

10

ChatGPT-User

0.1%

1.3%

+1.2 pp

2,825%

11

Applebot

1.9%

1.2%

-0.7 pp

-26%

12

Timpibot

0.3%

0.6%

+0.3 pp

133%

13

Baiduspider

0.5%

0.4%

-0.1 pp

7%

14

PerplexityBot

<0.01%

0.2%

+0.2 pp

157,490%

15

DuckDuckBot

0.2%

0.1%

-0.1 pp

-16%

16

SeznamBot

0.1%

0.1%

2%

17

Yeti

0.1%

0.1%

47%

18

coccocbot

0.1%

0.1%

-3%

19

Sogou

0.1%

0.1%

-22%

20

Yahoo! Slurp

0.1%

0.0%

-0.1 pp

-8%

Rank Bot name Share May 2024 Share May 2025 Δ percentage-point change Raw requests growth (May 2024 to May 2025)
1 Googlebot 30% 50% +20 pp 96%
2 Bingbot 10% 8.7% -1.3 pp 2%
3 GPTBot 2.2% 7.7% +5.5 pp 305%
4 ClaudeBot 11.7% 5.4% -6.3 pp -46%
5 GoogleOther 4.4% 4.3% -0.1 pp 14%
6 Amazonbot 7.6% 4.2% -3.4 pp -35%
7 Googlebot-Image 4.5% 3.3% -1.2 pp -13%
8 Bytespider 22.8% 2.9% -19.8 pp -85%
9 Yandex 2.8% 2.2% -0.7 pp -10%
10 ChatGPT-User 0.1% 1.3% +1.2 pp 2,825%
11 Applebot 1.9% 1.2% -0.7 pp -26%
12 Timpibot 0.3% 0.6% +0.3 pp 133%
13 Baiduspider 0.5% 0.4% -0.1 pp 7%
14 PerplexityBot <0.01% 0.2% +0.2 pp 157,490%
15 DuckDuckBot 0.2% 0.1% -0.1 pp -16%
16 SeznamBot 0.1% 0.1% 2%
17 Yeti 0.1% 0.1% 47%
18 coccocbot 0.1% 0.1% -3%
19 Sogou 0.1% 0.1% -22%
20 Yahoo! Slurp 0.1% 0.0% -0.1 pp -8%

Based on this data, two major shifts in web crawling occurred between May 2024 and May 2025:

1. Some AI crawlers rose sharply.
GPTBot (from OpenAI) increased its share from 2.2% to 7.7% (+5.5 pp), with a 305% rise in requests. This underscores the data demand for training large language models like ChatGPT. GPTBot jumped from #9 in May 2024 to #3 in May 2025.

Another OpenAI crawler, ChatGPT-User, saw requests surge by 2,825%, reaching a 1.3% share. This reflects a large rise in ChatGPT user activity or API-based interactions that involve accessing web content. PerplexityBot (from Perplexity.ai), despite a small 0.2% share, recorded the highest growth rate: a staggering 157,490% increase in raw requests.

Meanwhile, some AI crawlers saw steep declines. ClaudeBot (Anthropic) fell from 11.7% to 5.4% of total traffic and dropped 46% in requests. Bytespider plummeted 85% in request volume, falling from #2 to #8 in crawler share (now at just 2.9%).

Both Amazonbot and Applebot, also considered AI crawlers, saw decreases in share and in raw requests (–35% and –26%, respectively).

2. Google’s dominance expanded.
Googlebot’s share rose from 30% to 50%, supporting search indexing, but potentially also having AI-related purposes (such as new AI Overviews in Google Search). And GoogleOther (the crawler introduced in 2023) also increased in crawling traffic, 14%. Other Google crawlers not in the top 20, like Googlebot-News, also grew significantly (+71% in requests). There’s a clear trend of growth in these Google-related web crawlers at a time when the company is investing heavily in combining AI with search.

Also in the search category, Bingbot’s share (from Microsoft) declined slightly from 10% to 8.7% (-1.3 pp), though its raw requests still grew modestly by 2%.

These trends show that web crawling is increasingly dominated by bots from Google and OpenAI, reflecting clear shifts over the course of a year. Google also appears to be adapting how it collects data to support both traditional search and AI-driven features.

Also worth noting is FriendlyCrawler, which no longer appears in the top 20 list as of May 2025 (now ranked #35). It was #14 in May 2024 with a 0.2% share, but saw a 100% drop in requests by May 2025. This bot is known to index and analyze website content, although its owner and purpose remain unclear. Typically, crawlers like this are used for improving search results, market research, or analytics.

robots.txt & AI bots: GPTBot leads twice

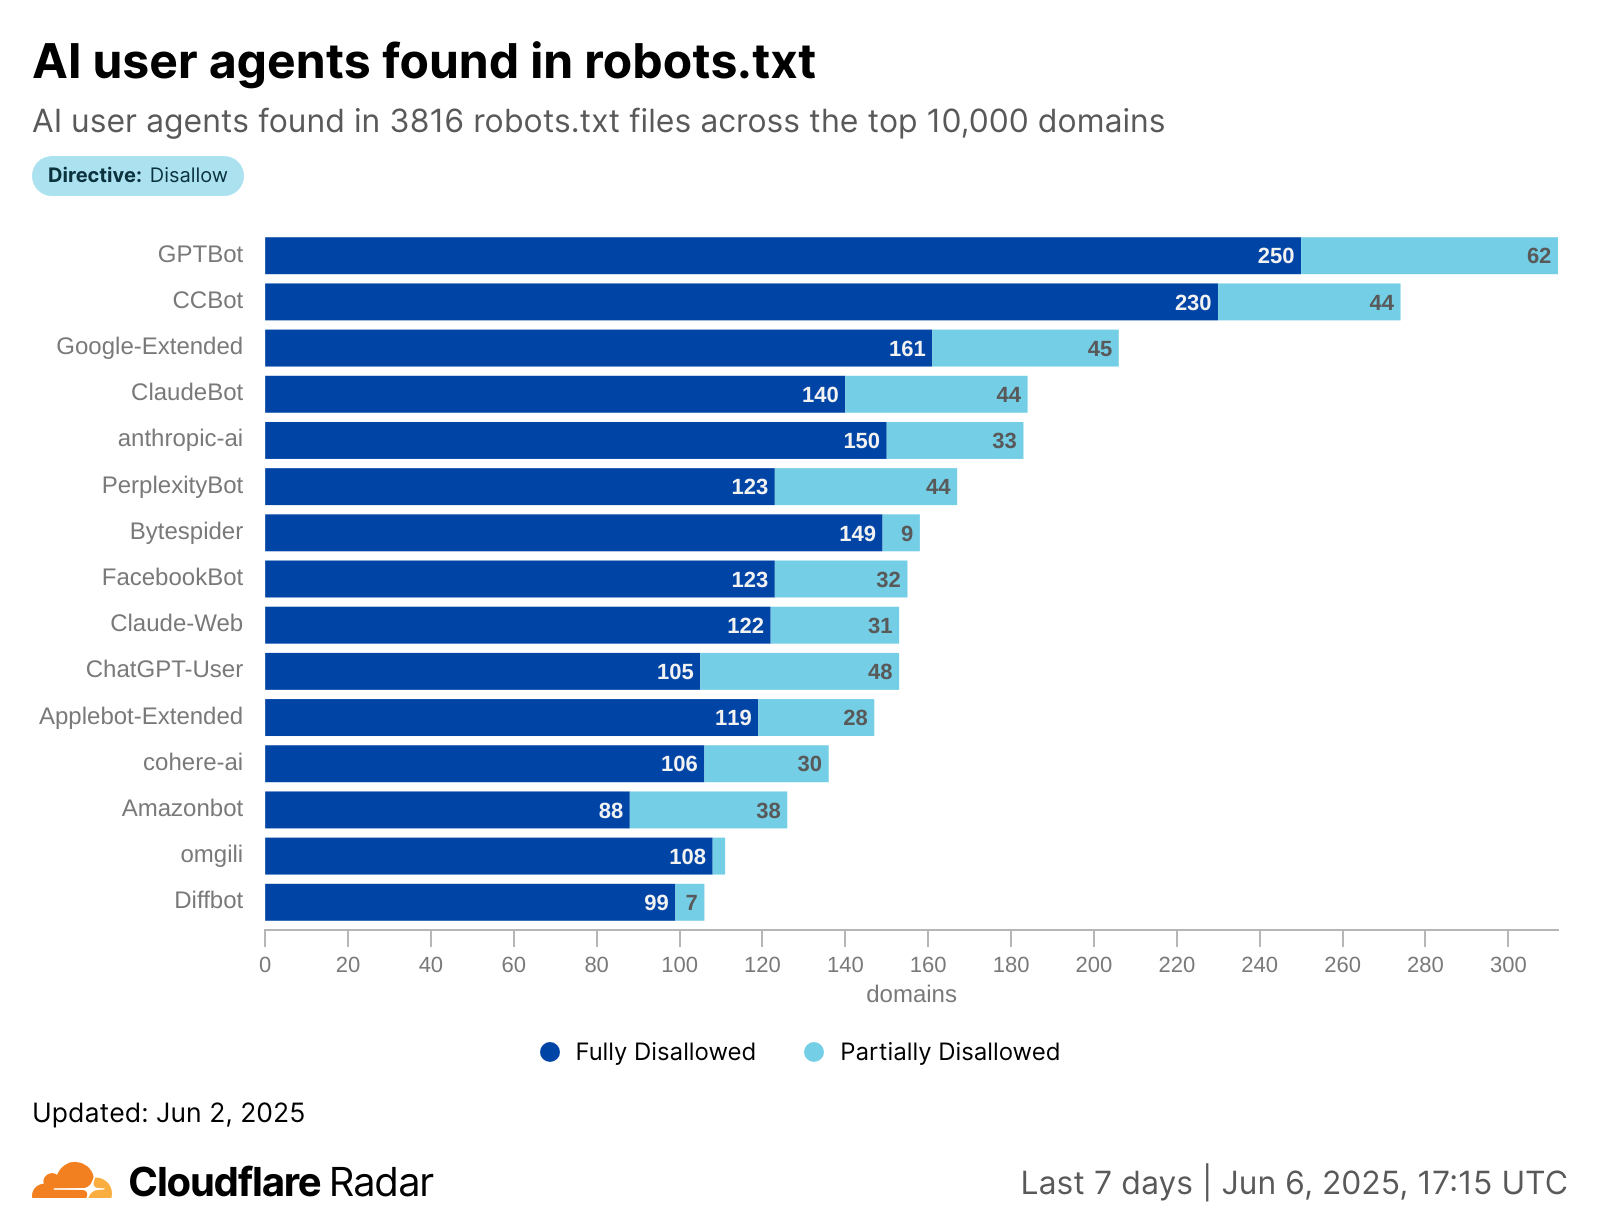
Recent data from June 6, 2025, from Cloudflare Radar shows that out of 3,816 domains (from the top 10,000) where we were able to find a robots.txt file, 546 (about 14%) had “allow” or “disallow” (fully or partially) directives targeting AI bots in particular.

This leaves many site owners in a gray area because it’s not always clear how effective robots.txt is in managing AI crawlers. Some site owners may not think to use it specifically for AI bots, while others might be unsure whether these bots even respect robots.txt rules, especially newer or less transparent crawlers. In other cases, sites use partial rules to fine-tune access, trying to balance visibility and protection without fully opting in or out.

The “disallow” rules appear far more often than “allow” rules. The most frequently blocked bot was GPTBot, disallowed by 312 domains (250 fully, 62 partially), followed by CCBot and Google-Extended, as shown in the following graph.


Although GPTBot was the most blocked, it was also the most explicitly allowed, with 61 domains granting access (18 fully, 43 partially). Still, very few sites openly and explicitly allow AI bots, and when they do, it’s usually for limited sections. Note that bots not listed in a site’s robots.txt are effectively allowed by default.

As AI crawling increases, more websites are moving from passive signals like robots.txt to active protections like Web Application Firewalls. The ecosystem is shifting, with a growing focus on enforceable controls.

Note: When we analyze crawler traffic, we compare user-agent tokens found in robots.txt files (like those for AI crawlers) with the actual user-agent strings in HTTP requests. It’s important to note that some robots.txt tokens, such as Google-Extended, aren’t user-agent substrings. As described in RFC 9309, one goal of these token may be to signal the purpose of the crawler. For instance, Google uses Google-Extended in robots.txt to see if your content can be used for AI training, but the traffic itself still comes from standard Google user-agents like Googlebot. Because of this, not every robots.txt entry will have a direct match in HTTP request logs.

Conclusion

As AI crawlers reshape the Internet, websites face both new challenges and new opportunities in managing their online presence.

This analysis highlights the growing impact of AI on web crawling, showing a clear shift from traditional search indexing to data collection for training AI models. The detailed statistics, such as Googlebot’s continued growth and the rapid rise of AI-specific crawlers, offer context for understanding how this space is evolving and what it means for the future of web content access.

The trend toward stronger, enforceable blocking methods, something Cloudflare has also been invested, signals a key shift in how websites may control their interactions with AI systems going forward.

Message Signatures are now part of our Verified Bots Program, simplifying bot authentication

Post Syndicated from Mari Galicer original https://blog.cloudflare.com/verified-bots-with-cryptography/

As a site owner, how do you know which bots to allow on your site, and which you’d like to block? Existing identification methods rely on a combination of IP address range (which may be shared by other services, or change over time) and user-agent header (easily spoofable). These have limitations and deficiencies. In our last blog post, we proposed using HTTP Message Signatures: a way for developers of bots, agents, and crawlers to clearly identify themselves by cryptographically signing requests originating from their service. 

Since we published the blog post on Message Signatures and the IETF draft for Web Bot Auth in May 2025, we’ve seen significant interest around implementing and deploying Message Signatures at scale. It’s clear that well-intentioned bot owners want a clear way to identify their bots to site owners, and site owners want a clear way to identify and manage bot traffic. Both parties seem to agree that deploying cryptography for the purposes of authentication is the right solution.     

Today, we’re announcing that we’re integrating HTTP Message Signatures directly into our Verified Bots Program. This announcement has two main parts: (1) for bots, crawlers, and agents, we’re simplifying enrollment into the Verified Bots program for those who sign requests using Message Signatures, and (2) we’re encouraging all bot operators moving forward to use Message Signatures over existing verification mechanisms. Because Verified Bots are considered authenticated, they do not face challenges from our Bot Management to identify as bots, given they’re already identified as such.

For site owners, no additional action is required – Cloudflare will automatically validate signatures on our edge, and if that validation is a success, that traffic will be marked as verified so that site owners can use the verified bot fields to create Bot Management and WAF rules based on it.  

This isn’t just about simplifying things for bot operators — it’s about giving website owners unparalleled accuracy in identifying trusted bot traffic, cutting down on the overhead for cryptographic verification, and fundamentally transforming how we manage authentication across the Cloudflare network.

Become a Verified Bot with Message Signatures

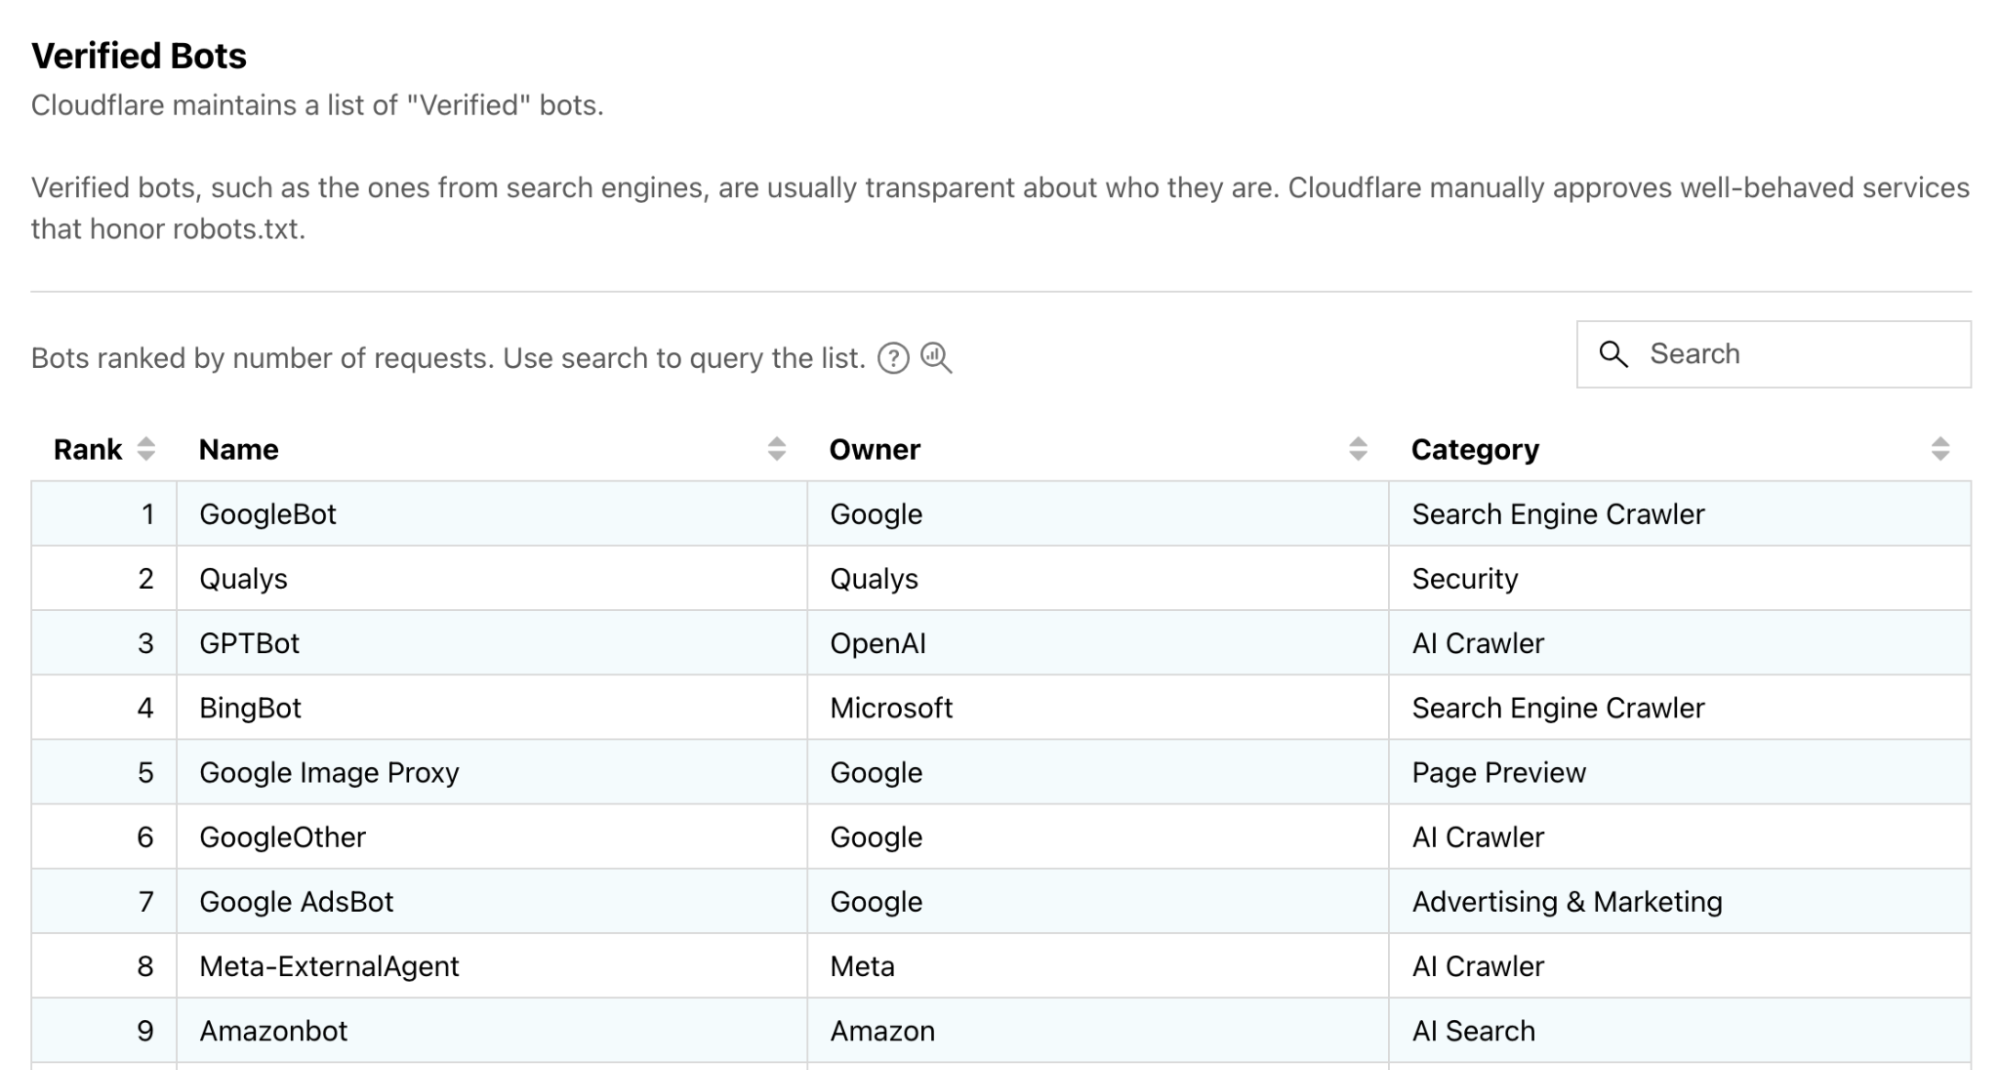
Cloudflare’s existing Verified Bots program is for bots that are transparent about who they are and what they do, like indexing sites for search or scanning for security vulnerabilities. You can see a list of these verified bots in Cloudflare Radar:


A preview of the Verified Bots page on Cloudflare Radar. 

In the past, in order to apply to be a verified bot, we used to ask for IP address ranges or reverse DNS names so that we could verify your identity. This required some manual steps like checking that the IP address range is valid and is associated with the appropriate ASN. 

With the integration of Message Signatures, we’re aiming to streamline applications into our Verified Bot program. Bots applying with well-formed Message Signatures will be prioritized, and approved more quickly! 

Getting started

In order to make generating Message Signatures as easy as possible, Cloudflare is providing two open source libraries: a web-bot-auth library in rust, and a web-bot-auth npm package in TypeScript. If you’re working on a different implementation, let us know – we’d love to add it to our developer docs!

At a high level, signing your requests with web bot auth consists of the following steps: 

  • Generate a valid signing key. See Signing Key section for step-by-step instructions.

  • Host a JSON web key set containing your public key under /.well-known/http-message-signature-directory of your website.

  • Sign responses for that URL using a Web Bot Auth library, one signature for each key contained in it, to prove you own it. See the Hosting section for step-by-step instructions.

  • Register that URL with us, using our Verified Bots form. This can be done directly in your Cloudflare account. See our documentation.

  • Sign requests using a Web Bot Auth library. 

As an example, Cloudflare Radar’s URL Scanner lets you scan any URL and get a publicly shareable report with security, performance, technology, and network information. Here’s an example of what a well-formed signature looks like for requests coming from URL Scanner:

GET /path/to/resource HTTP/1.1
Host: www.example.com
User-Agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/119.0.0.0 Safari/537.36
Signature-Agent: "https://web-bot-auth-directory.radar-cfdata-org.workers.dev"
Signature-Input: sig=("@authority" "signature-agent");\
             	 created=1700000000;\
             	 expires=1700011111;\
             	 keyid="poqkLGiymh_W0uP6PZFw-dvez3QJT5SolqXBCW38r0U";\
             	 tag="web-bot-auth"
Signature:sig=jdq0SqOwHdyHr9+r5jw3iYZH6aNGKijYp/EstF4RQTQdi5N5YYKrD+mCT1HA1nZDsi6nJKuHxUi/5Syp3rLWBA==:

Since we’ve already registered URLScanner as a Verified Bot, Cloudflare will now automatically verify that the signature in the Signature header matches the request — more on that later.

Register your bot

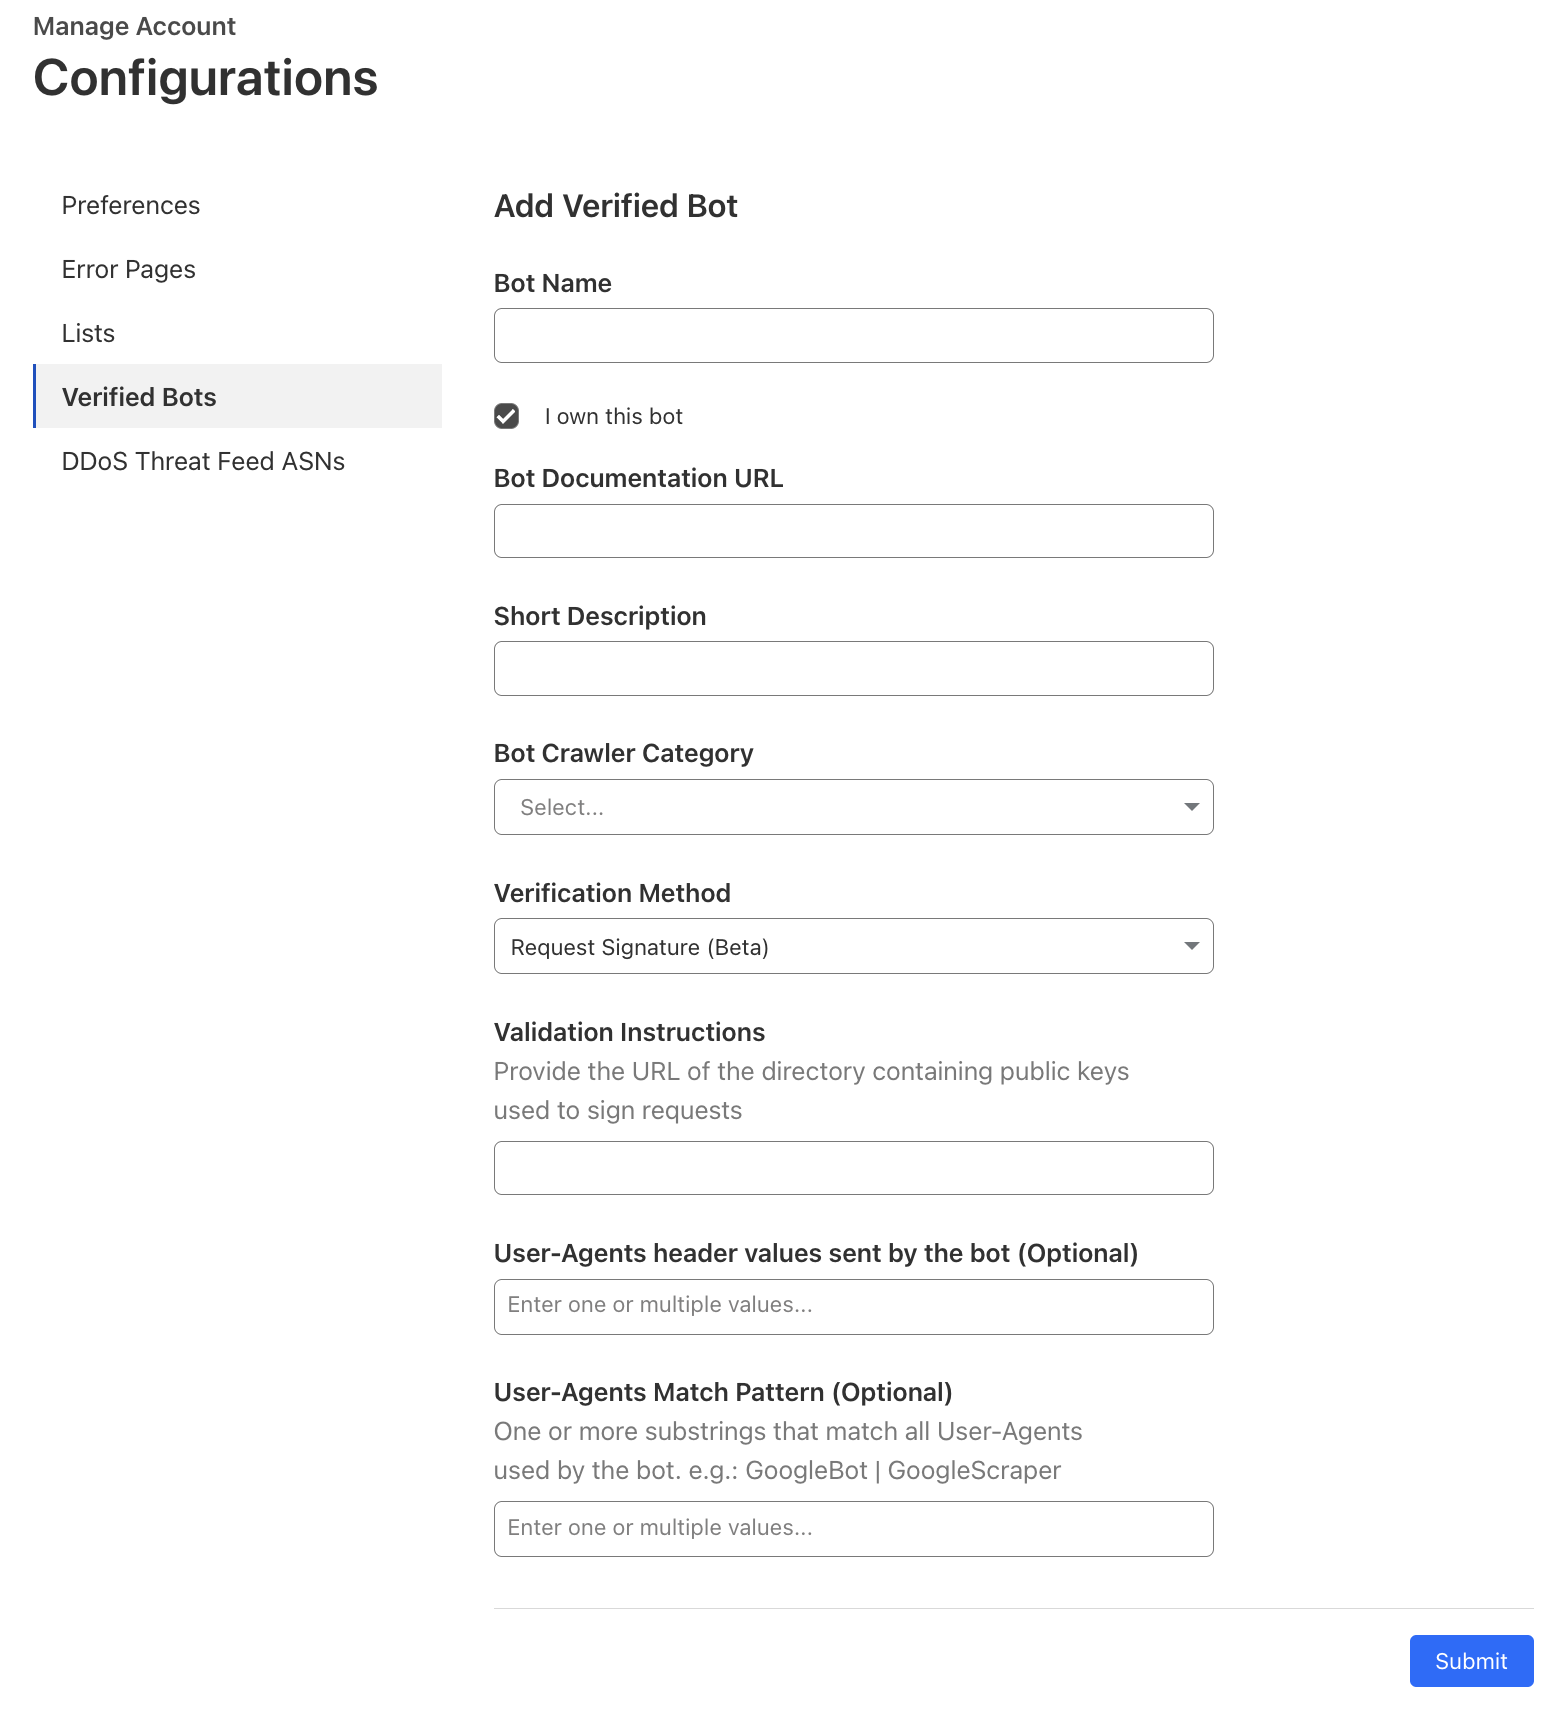
Access the Verified Bots submission form on your account. If that link does not immediately take you there, go to your Cloudflare account →  Account Home  → the three dots next to your account name  → Configurations → Verified Bots.


If you do not have a Cloudflare account, you can sign up for a free one.

For the verification method, select “Request Signature”, then enter the URL of your key directory in Validation Instructions. Specifying the User-Agent values is optional if you’re submitting a Request Signature bot. 

Once your application has gone through our (now shortened) review process, you don’t need to take any further action.

Message Signature verification for origins

Starting today, Cloudflare is ramping up verification of cryptographic signatures provided by automated crawlers and bots. This is currently available for all Free and Pro plans, and as we continue to test and validate at scale, will be released to all Business and Enterprise plans. This means that as time passes, the number of unauthenticated web crawlers should diminish, ensuring most bot traffic is authenticated before it reaches your website’s servers, helping to prevent spoofing attacks. 

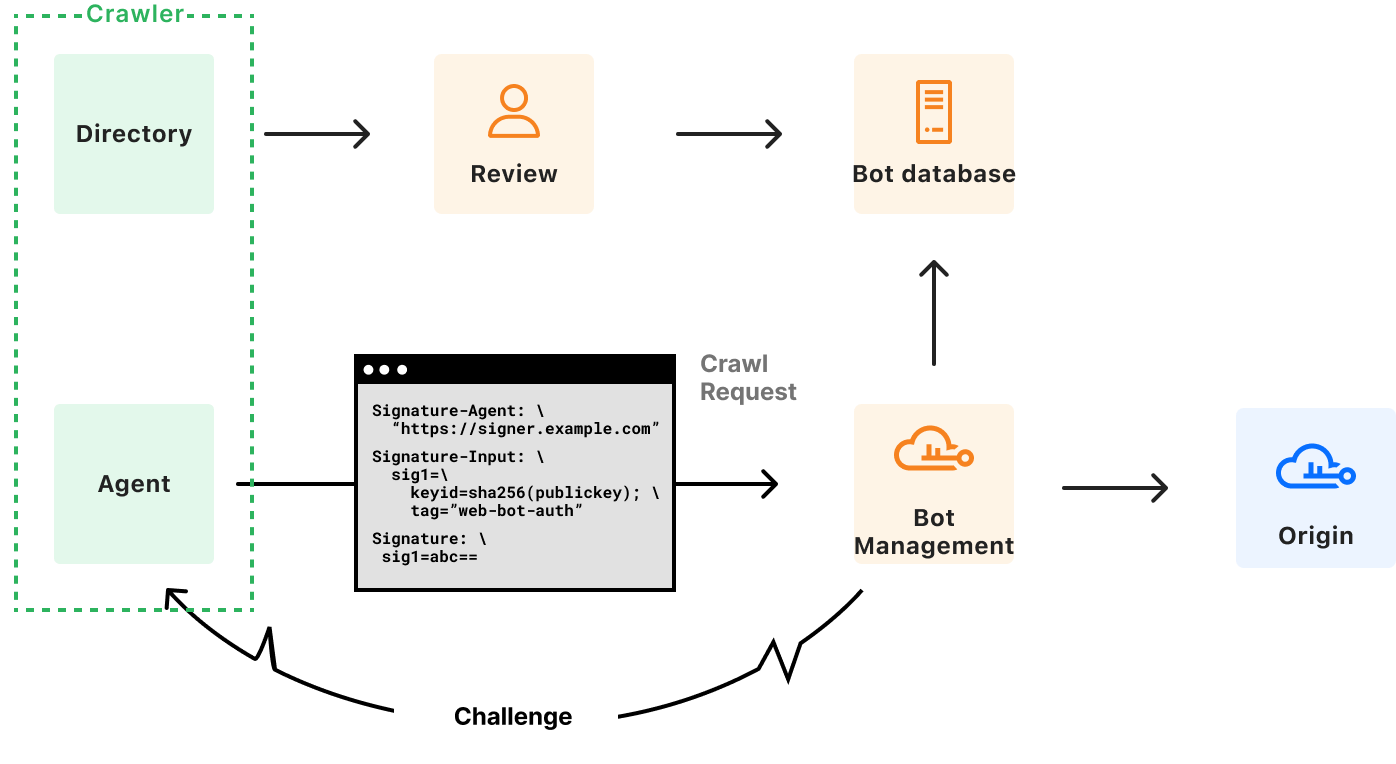
At a high level, signature verification works like this: 

  1. A bot or agent sends a request to a website behind Cloudflare.

  2. Cloudflare’s Message Signature verification service checks for the Signature, Signature-Input, and Signature-Agent headers.

  3. It checks that the incoming request presents a keyid parameter in your Signature-Input that points to a key we already know.

  4. It looks at the expires parameter in the incoming bot request. If the current time is after expiration, verification fails. This guards against replay attacks, preventing malicious agents from trying to pass as a bot by retrying messages they captured in the past.

  5. It checks that you’ve specified a tag parameter indicating web-bot-auth, to indicate your intent that the message be handled using web bot authentication specifically

  6. It looks at all the components chosen in your Signature-Input header, and constructs a signature base from it. 

  7. If all pre-flight checks pass, Cloudflare attempts to verify the signature base against the value in Signature field using an ed25519 verification algorithm and the key supplied in keyid.

  8. Verified Bots and other systems at Cloudflare use a successful verification as proof of your identity, and apply rules corresponding to that identity. 

If any of the above steps fail, Cloudflare falls back to existing bot identification and mitigation mechanisms. As the system matures, we would strengthen these requirements, and limit the possibilities of a soft downgrade.


As a site owner, you can segment your Verified Bot traffic by its type and purpose by adding the Verified Bot Categories field cf.verified_bot_category as a filter criterion in WAF Custom rules, Advanced Rate Limiting, and Late Transform rules. For instance, to allow the Bibliothèque nationale de France and the Library of Congress, and institutions dedicated to academic research, you can add a rule that allows bots in the Academic Research category.

Where we’re going next

HTTP Message Signatures is a primitive that is useful beyond Cloudflare – the IETF standardized it as part of RFC 9421.

As discussed in our previous blog post, Cloudflare believes that making Message Signatures a core component of bot authentication on the web should follow the same path. The specifications for the protocol are being built in the open, and they have already evolved following feedback.

Moreover, due to widespread interest, the IETF is considering forming a working group around Web Bot Auth. Should you be a crawler, an origin, or even a CDN, we invite you to provide feedback to ensure the solution gets stronger, and suits your needs.

A better, more trusted Internet

For bot, agent, and crawler operators that act transparently and provide vital services for the Internet, we’re providing a faster and more automated path to being recognized as a Verified Bot, reducing manual processes. We trust that this approach improves bot authentication from what were formerly brittle and unreliable authentication methods, to a secure and reliable alternative. It should reduce the overall volume of friction and hurdles genuinely useful bots face.

For site owners, Message Signatures provides better assurance that the bot traffic is legitimate — automatically recognized and allowed, minimizing disruption to essential services (e.g., search engine indexing, monitoring). In line with our commitments to making TLS/SSL and Post-Quantum certificates available for everyone, we’ll always offer the cryptographic verification of Message Signatures for all sites because we believe in a safer and more efficient Internet by fostering a trusted environment for both human and automated traffic.

If you have a feature request, feedback, or are interested in partnering with us, please reach out.

Изпращайте сигнали за държавните имоти планирани за разпродажба

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2025/signali-4400/

Това, че от Министерски съвет все пак публикуваха списъка с онези над 4400 имота и сгради, които на 8-ми май обявиха, че ще продават, създаде доста вълни. Имаше, разбира се, много възмущение, особено заради фрапантни случаи като това, че се продава комина на Пирогов, части от язовири и защитени местности. Да се открият тези места помогна интерактивната карта, която направих преди четири дни.

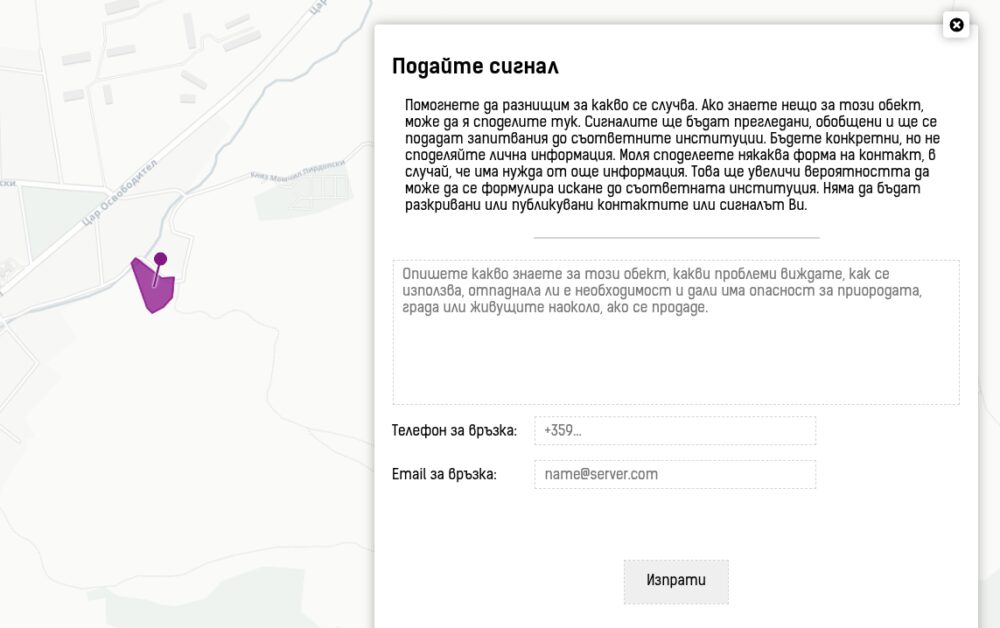
Тази карта позволи да видим списъка по начин, по който съм убеден, че дори гласувалите в Министерски съвет не са осъзнавали. Въпреки това, самият обем информация не позволява да се открият конкретни проблеми, фрапантни случаи, спорни казуси и злоупотреби по места. Тази информация е локална и трябва да я съберем преди министерства, агенции и държавни компании са се разбързали. Затова направих прост формуляр, с който да подавате какво знаете за вашия район. Това е подобно на помощта, която търсех за 3D картата със застрояването в София. Това може да е дали имотът или сградата е наистина изоставена или наскоро ремонтирана, дали вече няма някой частен субект, който да я обитава или какъв ефект ще има продажба над града и околната среда.

Формулярът за сигнали за отделни имоти в списъка на Желязков

Сигналите ще бъдат прегледани и ще бъдат отправени официални искания, включително в Народното събрание, към съответните министерства. Препоръчвам да оставите някаква форма на контакт, в случай, че е нужна допълнителна информация. Те няма да се публикуват никъде. Не оставяйте никаква лична информация, която да ви идентифицира в самия сигнал.

Формулярът за сигнали се отваря с линка „подай сигнал“ под всеки обект на картата. Вече е достъпна и извън предишната ми статия на този адрес. Надявам се да може да съберем достатъчно сигнали и да имаме възможност да ги прегледаме с всички, които се отзоваха да помагат, включително такива в парламента.

Междувременно, от МРРБ са обявили – без да споменават списъка или картата ми – че ще има тепърва анализ кои имоти действителност са с отпаднала нужда и кои да се продават. Дадоха индикация, че процесът на продажба е спрян докато това не се случи. Това е противоречи рязко на изказването преди два месеца на Желязков, че анализът е готов и незабавно ще започнат да се продават където има заявен (неясно как) частен интерес. Това говори само, че прозрачността и общественото внимание е помогнало и дава време да задаваме правилните въпроси за местата, които виждаме проблем.

Подобрения по картата

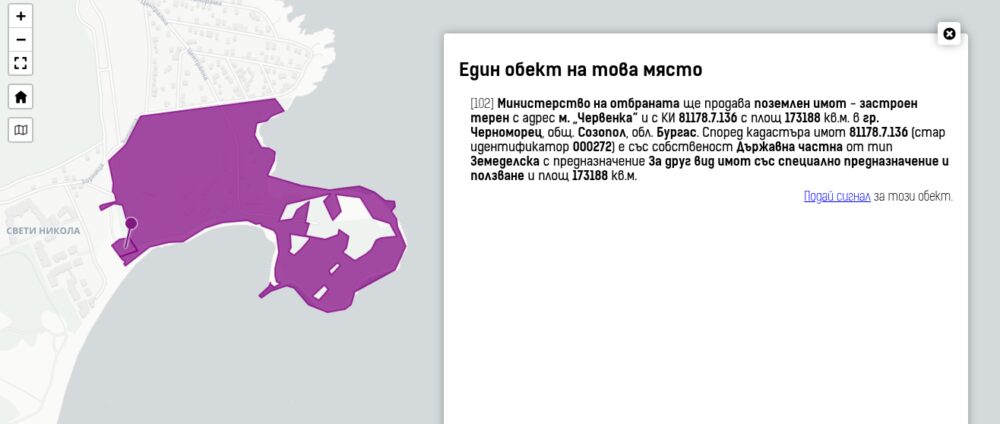
Междувременно, добавих няколко подобрения по картата. За по-малките имоти при увеличение на картата се показват пинчета, за да се забелязват по-лесно. Когато става въпрос за сгради и апартаменти се показва парцелът в лилаво и когато се отвори списъкът се виждат в червено конкретните обекти. Подобрих и групирането и представянето на имотите. Добавих и възможност да се линкват директно обекти. Т.е. като натиснете и извадите информация за даден обект, адреса на страницата се обновява автоматично, може да копирате и споделите точно какво гледате. Това ще позволи споделянето на конкретни случаи и притеснения. Това е например носът, който военните продават под Черноморец.

Нос край Черноморец, който се продава и за който отдавна има апетити

Когато е ясно точното местоположение съм добавил линк към картата в GovAlert, с която да търсите документи от градоустройството. Работи, за съжаление само за София, Пловдив и Благоевград, защото в останалите градове тези документи не са лесно достъпни или проследими. Работя сега да добавя и линк към картата с 3D сградите и застрояването в София.

Ако имате още предложения, притеснения или виждате проблем с картата или данните, моля споделете ги в коментарите тук.

The post Изпращайте сигнали за държавните имоти планирани за разпродажба first appeared on Блогът на Юруков.

A Code Club in every school and library

Post Syndicated from Philip Colligan, CBE original https://www.raspberrypi.org/blog/a-code-club-in-every-school-and-library/

Today we are starting a campaign to support every school and library in the UK to set up a free Code Club to make sure that all young people can develop the skills and knowledge they need to thrive in the age of AI.

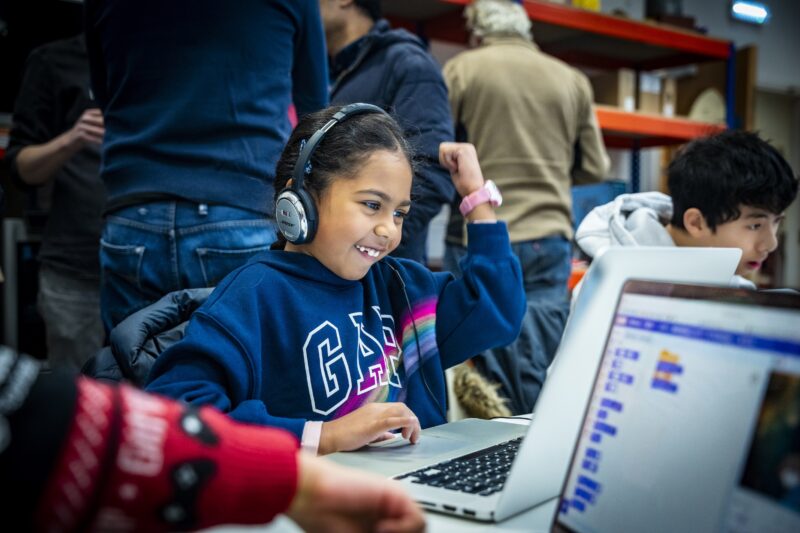
A young person celebrates at a Code Club.

Over the past decade, Code Club has provided more than 2 million young people with the opportunity to learn how to build their own apps, games, animations, websites, robots, and so much more. 

We know that getting hands-on, practical experience of building real projects with technology works. Independent evaluations have shown that attending a Code Club not only helps young people develop their programming skills, but also builds wider life skills such as confidence, resilience, problem-solving, and communication. All of which we know are essential if they are going to thrive in a world where AI is ubiquitous. 

Right now, there are over 2,000 Code Clubs meeting in schools and libraries all over the UK, organised by an amazing community of teachers, educators, and volunteers from all walks of life. We want to see that number grow. 

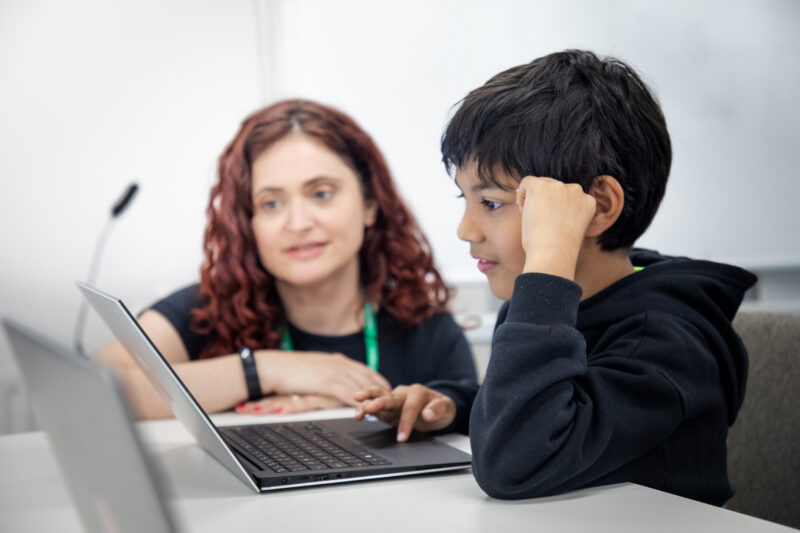
A young person and mentor at a Code Club.

You don’t need technical skills to mentor at a Code Club. The Raspberry Pi Foundation provides free, self-guided projects that help young people learn how to create with different technologies. We have over 200 Code Club Projects on our website, all of which are developed by expert educators, based on evidence of how young people learn, and rigorously tested; so we know that they are effective.

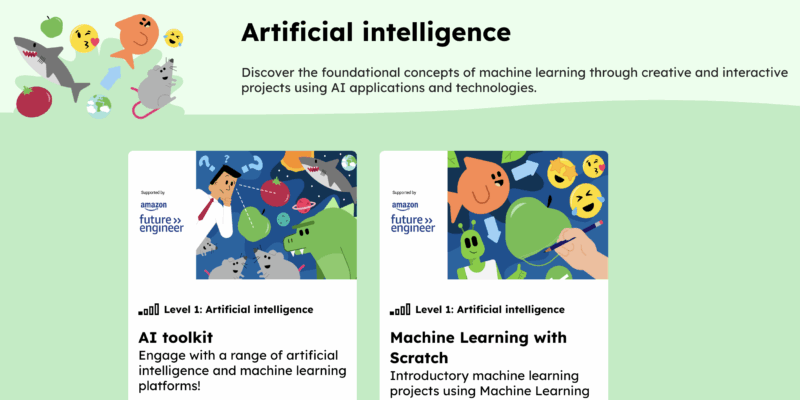
That includes a set of projects that support the safe exploration of AI technologies, helping young people understand how AI works, its possibilities and limitations.

A screenshot of the AI projects on our website.

We also provide training and support to help you set up and run your Code Club, all of which is available at no charge.  

I can promise you that the hour you spend in a Code Club will be the highlight of your week. I always come away from Code Club inspired and optimistic about what young people can achieve if we give them a sense of agency over technology.

Three young persons cheer at a Code Club.

If you have been inspired to set up your own Code Club, you can find all the information you need to run your own club here. 

You don’t have to take my word for it: here’s Janine, a Computer Science teacher and long-time Code Club mentor from Stoke-on-Trent sharing her experience.

Janine Kirk is a Computer Science Teacher at The King’s Church of England Academy in Stoke-on-Trent, UK, who has been running a Code Club for over ten years. She has been inspired by the campaign for a Code Club in every school and library in the UK, to set up clubs in six other schools in her multi-academy trust.

Philip Colligan and Janine Kirk at the recording of the Hello World podcast.
Philip and Janine Kirk at the recording of the Hello World podcast.

Setting up a Code Club is really easy as a teacher, as you can just tag it onto the end of your school day, or during lunch. The website is clear and easy to use — and once you have signed up, you have access to additional resources to promote your club. Code Club gives time and space to explore coding in a completely different way than in a classroom. For me, it’s about seeing what programs really inspire students: it gives an insight into how students like to code, ideas of preferred coding language, and tasks they keep coming back to. Running a Code Club has also allowed me to build relationships with students outside of the classroom environment, and all of this spills into my lessons and improves my teaching practice.

A young person connects a Raspberry Pi computer at a Code Club.

For students, Code Club is a great space where they can collaborate and work on their chosen tasks. Students often comment on how they look forward to Code Club and how they have continued their projects at home. It also allows students much more variety in enrichment activity, as Code Club is often popular with students who are neurodivergent. It’s amazing to see the children grow in confidence and friendship as they find likeminded students to support each other. 

My students really love the certificates they can earn. We have been inspired by the excellent activities that revamp the old ways of teaching programming and give them a really nice spin. In fact, I have used the resources in computer science lessons too, as they are often much more visual and fun for the students to create. 

A young person and mentor at a Code Club.

Since joining Code Club I have felt part of a community. I receive regular updates, and attending events such as the Clubs Conference really helps inspire creative ways to teach coding. As a computing teacher in a secondary school, you are often part of a very small team — but Code Club has allowed me to feel part of something bigger, and I know that should I need support, they are always there with friendly advice. It really is the best thing that I have done in my career.

Are you inspired to set up your own Code Club? Then find more information on how to get started running a club today.

The post A Code Club in every school and library appeared first on Raspberry Pi Foundation.

We’ve Issued Our First IP Address Certificate

Post Syndicated from Let's Encrypt original https://letsencrypt.org/2025/07/01/issuing-our-first-ip-address-certificate.html

Since Let’s Encrypt started issuing certificates in 2015, people have repeatedly requested the ability to get certificates for IP addresses, an option that only a few certificate authorities have offered. Until now, they’ve had to look elsewhere, because we haven’t provided that feature.

Today, we’ve issued our first certificate for an IP address, as we announced we would in January. As with other new certificate features on our engineering roadmap, we’ll now start gradually rolling out this option to more and more of our subscribers.

Some Background on IP Address Certs

IP addresses are the underlying numerical addresses used on the Internet. Every device on the Internet has one (though, in modern practice, it might be shared with other devices, like when an entire home network shares a single public IP address). The Internet infrastructure uses them to route communications to their proper destination. IP addresses come in two forms, IPv4 and IPv6, and generally look like 54.215.62.21 (IPv4) or 2600:1f1c:446:4900::65 (IPv6).

Most Internet users rarely see or refer to IP addresses directly. Instead, they almost always use domain names like letsencrypt.org to refer to Internet services. The domain name system (DNS) is a part of the Internet infrastructure that’s responsible for allowing software to find the IP addresses associated with a particular domain name. For instance, your web browser can use DNS to find out that the service https://letsencrypt.org/ (Let’s Encrypt’s own website) is provided from the IP addresses 54.215.62.21 and 2600:1f1c:446:4900::65, among several others. This probably happened behind the scenes before you started reading this article! Your web browser needed to know our IP address in order to actually connect to our site and fetch this article.

Because we overwhelmingly tend to think and talk about Internet services in terms of domain names, those are the identifiers that are normally listed in certificates like those that Let’s Encrypt provides to our subscribers. Since you know us as “letsencrypt.org” and not as, say, “54.215.62.21,” it makes the most sense for our domain name to be on our certificate. After all, that’s what you’ll want your web browser to check against. This also gives Internet services more flexibility to be hosted in multiple locations, or to change where they’re hosted, without necessarily needing separate certificates for each server.

In principle, there’s no reason that a certificate couldn’t be issued for an IP address rather than a domain name, and in fact the technical and policy standards for certificates have always allowed this, with a handful of certificate authorities offering this service on a small scale. In Let’s Encrypt’s case, we’ve preferred to wait until some other pieces, like short-lived certs, were in place before we made this option available for our subscribers.

Why IP Address Certs Are Less Common

First and foremost, it’s because Internet users usually know services by domain names, not by IP addresses, and because IP addresses can easily change “behind the scenes” with no prior notice. For instance, a popular site could switch from one cloud hosting company to a different one, and update its DNS records to point at the new host. Most users wouldn’t ever notice the change at all, even though the site’s underlying IP addresses would be completely different.

Second, because IP addresses can change so easily, the sense of “ownership” one might have for them—or that a certificate authority might be able to attest to—tends to be weaker than for a domain name. If you’re hosting something in your house on a residential broadband connection, your Internet service provider most likely doesn’t guarantee that your IP address will stay the same over time. (That is, most home Internet users have a “dynamic IP address” from their ISPs, rather than a “static IP address.”) In that case, you have to contend with the possibility that that address may change often, possibly without warning, and that your old address may be assigned to somebody else.

Third, most Internet service operators don’t expect that end users will ever intentionally connect to their sites directly by IP address. In some cases, when an IP address is shared by different websites or different devices, connecting by IP address alone wouldn’t even work properly. In that case, there’s not much benefit to obtaining a certificate for the IP address!

How Let’s Encrypt Subscribers May Use IP Address Certs

Most current subscribers should be fine with their existing domain name certs and won’t need IP address certs. Subscribers who have a use for an IP address cert are typically already aware of that. A few use cases that we’re aware of include:

  • A default page for hosting providers, in case someone pastes a server’s IP address into a browser instead of an individual site name (right now, this normally produces an error in the browser).

  • A way to access your website if you don’t have a domain name at all (at some cost in reliability and convenience compared to getting a domain name).

  • Securing DNS over HTTPS (DoH) or other infrastructure services. Having a certificate makes it much easier for DoH servers to prove their identities to clients. That could make it more feasible for DoH users or clients to enforce a requirement for a valid publicly-trusted certificate when connecting to DoH servers.

  • Securing remote access to some home devices (like network-attached storage servers and Internet-of-things devices) even without a domain name.

  • Securing ephemeral connections within cloud hosting infrastructure, like connections between one back-end cloud server and another, or ephemeral connections to administer new or short-lived back-end servers via HTTPS—as long as those servers have at least one public IP address available.

How To Get an IP Address Cert

IP address certificates are available right now in Staging. They should be generally available in Prod later in 2025, at the same time that short-lived certificates become generally available. Prior to general availability we may allow list issuance for a limited number of partners who can provide us with feedback.

Many Let’s Encrypt client applications should already be able to request certificates for IP addresses, although there can be minor technical changes required to support this in some client software.

As a matter of policy, Let’s Encrypt certificates that cover IP addresses must be short-lived certs, valid for only about six days. As such, your ACME client must support the draft ACME Profiles specification, and you must configure it to request the shortlived profile. And, probably not surprisingly, you can’t use the DNS challenge method to prove your control over an IP address; only the http-01 and tls-alpn-01 methods can be used.

If your client software requests an IP address cert with details that aren’t compatible with these policies, the order will be rejected by the ACME server. In this case, your client application may need to be updated or reconfigured. Feel free to ask for help on the Let’s Encrypt community forum if you encounter any problems, either as a client application developer or as an end user.

We’ve Issued Our First IP Address Certificate

Post Syndicated from Let's Encrypt original https://letsencrypt.org/2025/07/01/issuing-our-first-ip-address-certificate/

Since Let’s Encrypt started issuing certificates in 2015, people have repeatedly requested the ability to get certificates for IP addresses, an option that only a few certificate authorities have offered. Until now, they’ve had to look elsewhere, because we haven’t provided that feature.

Today, we’ve issued our first certificate for an IP address, as we announced we would in January. As with other new certificate features on our engineering roadmap, we’ll now start gradually rolling out this option to more and more of our subscribers.

Some Background on IP Address Certs

IP addresses are the underlying numerical addresses used on the Internet. Every device on the Internet has one (though, in modern practice, it might be shared with other devices, like when an entire home network shares a single public IP address). The Internet infrastructure uses them to route communications to their proper destination. IP addresses come in two forms, IPv4 and IPv6, and generally look like 54.215.62.21 (IPv4) or 2600:1f1c:446:4900::65 (IPv6).

Most Internet users rarely see or refer to IP addresses directly. Instead, they almost always use domain names like letsencrypt.org to refer to Internet services. The domain name system (DNS) is a part of the Internet infrastructure that’s responsible for allowing software to find the IP addresses associated with a particular domain name. For instance, your web browser can use DNS to find out that the service https://letsencrypt.org/ (Let’s Encrypt’s own website) is provided from the IP addresses 54.215.62.21 and 2600:1f1c:446:4900::65, among several others. This probably happened behind the scenes before you started reading this article! Your web browser needed to know our IP address in order to actually connect to our site and fetch this article.

Because we overwhelmingly tend to think and talk about Internet services in terms of domain names, those are the identifiers that are normally listed in certificates like those that Let’s Encrypt provides to our subscribers. Since you know us as “letsencrypt.org” and not as, say, “54.215.62.21,” it makes the most sense for our domain name to be on our certificate. After all, that’s what you’ll want your web browser to check against. This also gives Internet services more flexibility to be hosted in multiple locations, or to change where they’re hosted, without necessarily needing separate certificates for each server.

In principle, there’s no reason that a certificate couldn’t be issued for an IP address rather than a domain name, and in fact the technical and policy standards for certificates have always allowed this, with a handful of certificate authorities offering this service on a small scale. In Let’s Encrypt’s case, we’ve preferred to wait until some other pieces, like short-lived certs, were in place before we made this option available for our subscribers.

Why IP Address Certs Are Less Common

First and foremost, it’s because Internet users usually know services by domain names, not by IP addresses, and because IP addresses can easily change “behind the scenes” with no prior notice. For instance, a popular site could switch from one cloud hosting company to a different one, and update its DNS records to point at the new host. Most users wouldn’t ever notice the change at all, even though the site’s underlying IP addresses would be completely different.

Second, because IP addresses can change so easily, the sense of “ownership” one might have for them—or that a certificate authority might be able to attest to—tends to be weaker than for a domain name. If you’re hosting something in your house on a residential broadband connection, your Internet service provider most likely doesn’t guarantee that your IP address will stay the same over time. (That is, most home Internet users have a “dynamic IP address” from their ISPs, rather than a “static IP address.”) In that case, you have to contend with the possibility that that address may change often, possibly without warning, and that your old address may be assigned to somebody else.

Third, most Internet service operators don’t expect that end users will ever intentionally connect to their sites directly by IP address. In some cases, when an IP address is shared by different websites or different devices, connecting by IP address alone wouldn’t even work properly. In that case, there’s not much benefit to obtaining a certificate for the IP address!

How Let’s Encrypt Subscribers May Use IP Address Certs

Most current subscribers should be fine with their existing domain name certs and won’t need IP address certs. Subscribers who have a use for an IP address cert are typically already aware of that. A few use cases that we’re aware of include:

  • A default page for hosting providers, in case someone pastes a server’s IP address into a browser instead of an individual site name (right now, this normally produces an error in the browser).

  • A way to access your website if you don’t have a domain name at all (at some cost in reliability and convenience compared to getting a domain name).

  • Securing DNS over HTTPS (DoH) or other infrastructure services. Having a certificate makes it much easier for DoH servers to prove their identities to clients. That could make it more feasible for DoH users or clients to enforce a requirement for a valid publicly-trusted certificate when connecting to DoH servers.

  • Securing remote access to some home devices (like network-attached storage servers and Internet-of-things devices) even without a domain name.

  • Securing ephemeral connections within cloud hosting infrastructure, like connections between one back-end cloud server and another, or ephemeral connections to administer new or short-lived back-end servers via HTTPS—as long as those servers have at least one public IP address available.

How To Get an IP Address Cert

IP address certificates are available right now in Staging. They should be generally available in Prod later in 2025, at the same time that short-lived certificates become generally available. Prior to general availability we may allow list issuance for a limited number of partners who can provide us with feedback.

Many Let’s Encrypt client applications should already be able to request certificates for IP addresses, although there can be minor technical changes required to support this in some client software.

As a matter of policy, Let’s Encrypt certificates that cover IP addresses must be short-lived certs, valid for only about six days. As such, your ACME client must support the draft ACME Profiles specification, and you must configure it to request the shortlived profile. And, probably not surprisingly, you can’t use the DNS challenge method to prove your control over an IP address; only the http-01 and tls-alpn-01 methods can be used.

If your client software requests an IP address cert with details that aren’t compatible with these policies, the order will be rejected by the ACME server. In this case, your client application may need to be updated or reconfigured. Feel free to ask for help on the Let’s Encrypt community forum if you encounter any problems, either as a client application developer or as an end user.

AWS Certificate Manager now supports exporting public certificates

Post Syndicated from Pravin Nair original https://aws.amazon.com/blogs/security/aws-certificate-manager-now-supports-exporting-public-certificates/

AWS Certificate Manager (ACM) simplifies the provisioning, management, and deployment of public and private TLS certificates for AWS services and your on-premises and hybrid applications. To further enhance the flexibility of ACM for diverse workloads, we’re introducing a powerful new capability: ACM exportable public certificates. You can use this capability to export public TLS certificates and associated private keys from ACM, which can be used to secure workloads on Amazon Elastic Compute Cloud (Amazon EC2) instances, Amazon Elastic Kubernetes Service (Amazon EKS) pods, on-premises servers, or servers hosted with other cloud providers. The capability supports public certificates that are newly created in your AWS account

In this post, we show you how to automate the export and distribution of public exportable certificates across a diverse infrastructure. We walk you through creating workflows that automatically deliver certificates to multiple destinations including EC2 instances and virtual machines in hybrid environments. We explore how this automation works, its benefits, and provide a step-by-step guide to get started. Additionally, we explore how you can use integration with Amazon EventBridge to trigger automatic certificate exports when certificates are issued or renewed, streamlining certificate deployment across heterogeneous environments and significantly reducing management overhead.

Background: ACM and certificate management

ACM is a managed service that removes the complexity of purchasing, uploading, and renewing TLS certificates. It provides public certificates at no additional cost for AWS services integrated with ACM such as Elastic Load Balancing (ELB), Amazon CloudFront, and Amazon API Gateway. ACM also supports importing third-party public certificates and issuing private certificates through AWS Private Certificate Authority. Prior to this release, ACM public certificates were designed for AWS services integrated with ACM such as CloudFront, providing seamless TLS encryption for those services. For use cases involving third-party content delivery networks (CDNs) or workloads terminating TLS on EC2 instances, customers typically sourced certificates from other providers or imported them into ACM for centralized management. Customers have told us that they would like to use ACM for these use cases, extending its simplicity and scalability to a wider range of environments. The new ACM exportable public certificates capability fulfills this need, enabling you to export ACM-managed public certificates for use with your custom workloads while maintaining centralized management and automated renewals.

With ACM you can now request a public certificate, validate domain ownership, and export the certificate for use with software that terminates TLS such as Apache, NGINX, or Microsoft IIS. ACM handles certificate renewals, reducing the risk of expirations that can disrupt your applications.

How it works: ACM public certificate issuance and renewal

To use ACM exportable public certificates, you need to understand how to automate certificate management using the issuance and renewal processes. In this section, we describe these processes and their automation capabilities, which are critical for deploying and maintaining certificates.

ACM public certificate issuance

Issuing an ACM public certificate involves the following steps:

  1. Request a certificate: In the AWS Management Console for ACM, or the AWS Command Line Interface (AWS CLI) or API, initiate a certificate request by specifying the domain names you want to secure (for example, example.com or *.example.com).
  2. Validate domain ownership: ACM requires that you prove control over the domain. If the domain is hosted on Amazon Route 53, you can request that ACM validate the domain ownership. For domains hosted outside AWS, you can use DNS validation (adding a CNAME record) or email validation (responding to emails sent to domain contacts).
  3. Certificate issuance: After the domain ownership has been validated, ACM issues the certificate, which includes the public key, private key, and certificate chain.
  4. Associate the certificate with an integrated AWS service: See Services integrated with ACM for information about associating the certificate with an integrated AWS service.
  5. Export the certificate: With the new capability you can now export the public certificate, private key, and certificate chain using the ACM console, AWS CLI, or API for use on servers that aren’t integrated with ACM.
  6. Bind to application: Install the exported certificate on your server (for example, Apache or NGINX) to enable TLS termination.

With the launch of this new capability, you can now control the future exportability of public certificates that you create in ACM.

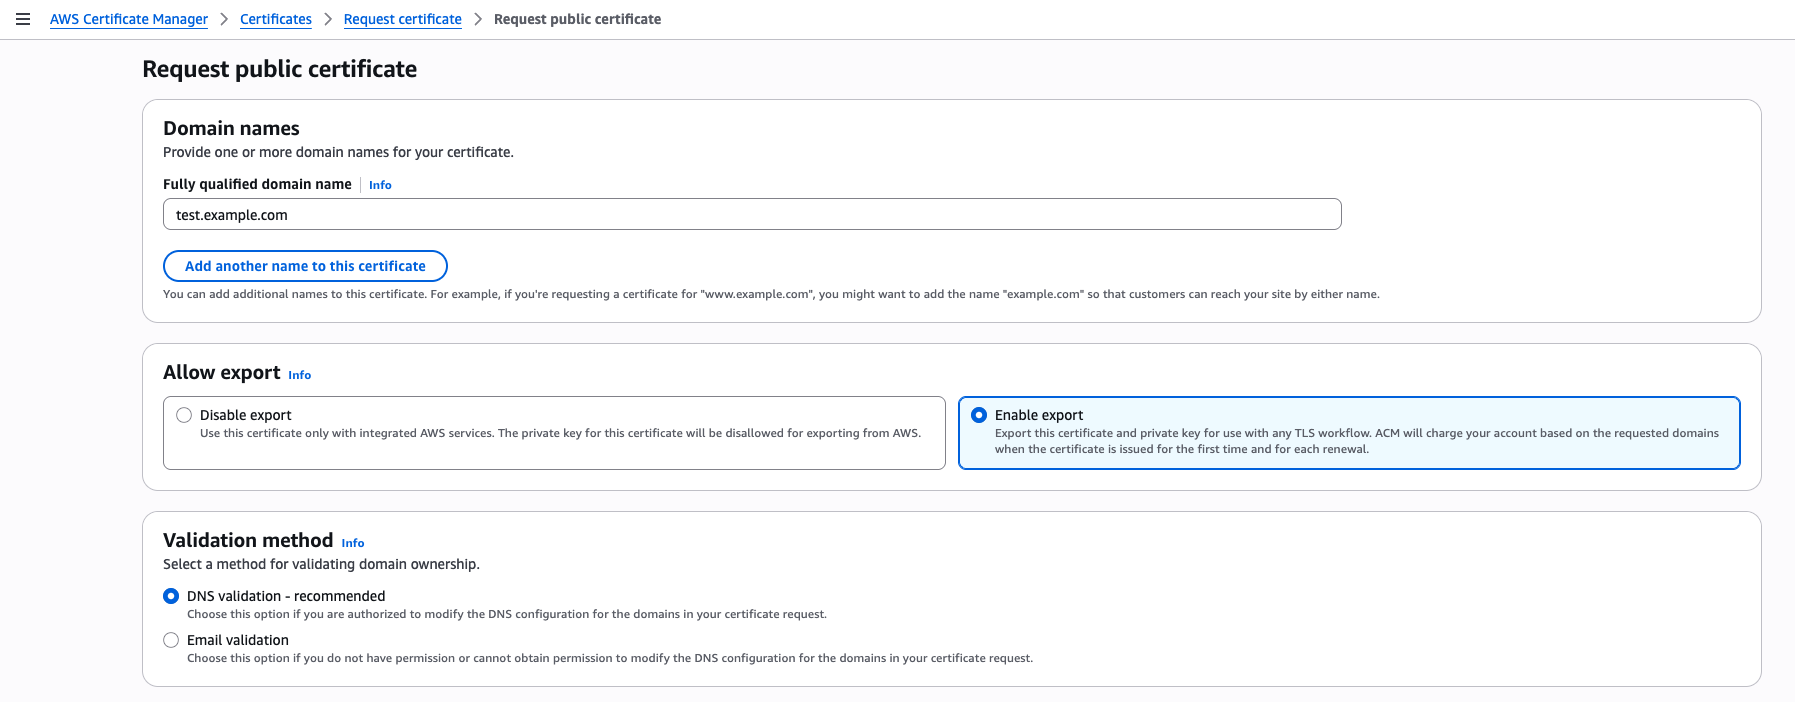
To create an exportable public certificate, use the ACM console to create a new public certificate. To get started, choose Request certificate in the ACM console and on the Request public certificate page, under Allow export, select Enable export. If you select Disable export, the private key for this certificate will be disallowed for exporting from ACM, which cannot be changed after certificate issuance.

Figure 1: Request a public certificate and enable export

Figure 1: Request a public certificate and enable export

After creating your certificate with the
Enable export option selected and completing domain ownership validation, you can proceed with the export process, as shown in Figure 2. To export your certificate, select it from the list of certificates, choose
More actions, and select
Export.

Figure 2: Export a certificate

Figure 2: Export a certificate

ACM public certificate renewal

ACM automates the process of certificate renewal, which includes:

  1. Renewal initiation: ACM automatically initiates renewal 60 days before a certificate expires.
  2. Domain revalidation: ACM revalidates domain ownership using the same method as the initial issuance (DNS or email).
  3. Certificate update: Upon successful revalidation, ACM issues a new certificate with the same Amazon Resource Name (ARN) with updated validity dates.
  4. When a certificate is renewed in ACM, the service automatically sends an EventBridge event to notify you that the new certificate is available. If the renewal fails, ACM sends notifications to both the AWS Health Dashboard and EventBridge. To stay informed about these certificate events, you can create EventBridge rules that monitor for specific certificate-related events. You can configure these rules to send notifications to an Amazon Simple Notification Service Amazon (SNS) topic so that interested parties receive timely updates about their certificate status.

New EventBridge schema fields: Following successful ACM certificate renewal, the ACM Certificate Available event now includes an exportable field that indicates with TRUE|FALSE whether the public certificate is ready to be exported.

{
    "version": "0",
    "id": "id", 
    "detail-type": "ACM Certificate Available",
    "source": "aws.acm",
    "account": "account",
    "time": "2019-12-22T18:43:48Z",
    "region": "region",
    "resources": [
        "arn:aws:acm:region:account:certificate/certificate_ID"
    ],
    "detail": {
       “Action” : "ISSUANCE" | "RENEWAL" | "IMPORT" | "REIMPORT",
       "CertificateType" : "AMAZON_ISSUED" | "PRIVATE" | "IMPORTED",    
       "CommonName": "example.com",     
       "DomainValidationMethod" : "EMAIL" | "DNS",    
       "CertificateCreatedDate" : "2019-12-22T18:43:48Z",
       "CertificateExpirationDate" : "2019-12-22T18:43:48Z",
       "DaysToExpiry" : 395,
       "InUse" : TRUE | FALSE,    
       "Exported" : TRUE | FALSE,
       "Exportable" : TRUE | FALSE   <== New     
     }
}
  1. Export and update: You can export the renewed certificate and update it on your servers manually or using EventBridge targets such as AWS Systems Manager Automation documents triggered by EventBridge rules. For more information, see Event bus targets in Amazon EventBridge.

You can use EventBridge rules to monitor specific events and route them to one or more targets (such as Amazon SNS topics, AWS Lambda functions, or other AWS services) for processing. For example, when domain validation fails because of DNS configuration issues, ACM generates an ACM Certificate Renewal Action Required EventBridge event. By creating an EventBridge rule that targets an SNS topic, you can subscribe to receive email alerts and take necessary corrective actions.

Automating deployment of renewed certificates using EventBridge

The certificate renewal process helps make sure that your TLS certificates remain valid without manual intervention, but updating certificates across diverse environments can still require effort. When ACM renews a certificate, it generates an EventBridge event. You can configure EventBridge rules to trigger targets based on this event, such as:

  • Send notifications: Route the event to Amazon SNS to send email or SMS notifications to administrators.
  • Automate certificate deployment: Trigger Lambda functions or Systems Manager Automation documents to retrieve the renewed certificate using the ACM API and update it on your servers.
  • Monitor renewal failures: Configure alerts based on ACM certificate renewal failure events. These events can be directly routed to notification channels to inform you about issues such as domain validation errors.

To set this up, create an EventBridge rule to match the ACM renewal event, specify a target, (such as an SNS topic or Lambda function). This automation minimizes manual intervention, helping to facilitate seamless certificate updates across your infrastructure.

Solution overview

In the section, we describe two workflows. The first demonstrates an automated process for exporting existing ACM public certificates and installing them on target EC2 instances or virtual machines. The second workflow is triggered when public certificates are automatically renewed by ACM when they become available in ACM, followed by updating these certificates on downstream EC2 instances and virtual machines. While this solution uses EC2 instances and virtual machines as the target systems, the same methods can be applied to refresh public certificates at scale across various types of systems.

Prerequisites

  1. To extend this automated public certificate export and update process to:
    1. Register EC2 instances: Follow the instructions in Managing EC2 instances with Systems Manager.
    2. Register on-premises and other cloud environments’ virtual machines: Follow the instructions in Managing nodes in hybrid and multicloud environments with Systems Manager.
  2. Add TargetTagKey tags to EC2 instances and virtual machines where you want to deploy renewed certificates. The automation uses these tags to identify target instances.
  3. The ExportCertificate API requires a certificate passphrase for operation. To maintain security best practices, we recommend storing passwords in encrypted form using password vaults instead of plain text storage. Our implementation uses AWS Secrets Manager to securely store these sensitive credentials. The solution also uses Amazon DynamoDB to maintain certificate metadata, which includes a reference to the corresponding secret name stored in Secrets Manager. For added security, the DynamoDB table’s data is automatically encrypted at rest using AWS Key Management Service (AWS KMS).

ACM certificate export

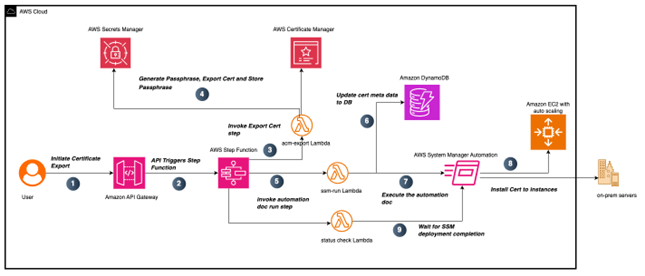
Figure 3: ACM certificate issuance and export workflow

Figure 3: ACM certificate issuance and export workflow

The workflow shown in Figure 3 demonstrates an automated process for exporting existing public ACM certificates through an API-driven process and deploying them to downstream systems.

  1. The process begins when a user makes a request to an API Gateway endpoint, providing essential parameters including the CertificateArn to identify the certificate you want to export, CertName for certificate identification, and TargetTagKey and TargetTagValue for identifying the target EC2 instances where you want this certificate to be installed. The following is an example of the payload sent to API Gateway:
    {
      "CertificateArn": "arn:aws:acm:us-east-1:1234567890123:certificate/8106d6b2-f204-4354-8893-d49e311b3900",
      "CertName": "academe",
      "TargetTagKey": "env",
      "TargetTagValue": "dev"
    }

  2. Upon receiving the request, API Gateway triggers an AWS Step Functions workflow containing multiple orchestrated states.
  3. The initial state executes a Lambda function named acm-Export, which generates a passphrase for the private key.
  4. The acm-Export lambda function also securely stores the generated passphrase in Secrets Manager and uses the generated passphrase to export the ACM certificate.
  5. After completing the acm-Export function, the Step Functions workflow invokes the Lambda ssm-run function.
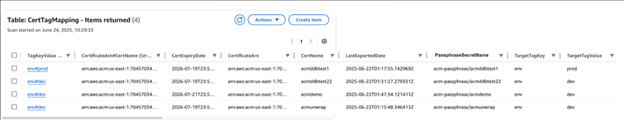
  6. This function performs two operations: it checks the certificate’s existence in DynamoDB (which serves as an inventory tracking system) and manages record-keeping. When the function encounters an existing certificateARN, it updates the record with the current CertExpiryDate and LastExportedDate timestamp values. For certificates being exported for the first time, the Lambda function creates a new record in DynamoDB if no matching entry exists. This new record captures the certificate’s metadata, including its details and tracking information. Figure 4 shows how this metadata is structured in a DynamoDB table entry in the console.
Figure 4: Certificate metadata in a DynamoDB table

Figure 4: Certificate metadata in a DynamoDB table

  1. Following the metadata verification step in DynamoDB, the Lambda function also initiates running a custom Systems Manager document called Install-ACMCertificate. This document handles the installation of newly exported public certificates onto specified EC2 instances. The same Systems Manager document can be used for certificate installation or updates onto on-premises servers, providing flexibility in certificate deployment.
  2. When the Systems Manager document execution succeeds, it deploys the newly exported public certificates to EC2 instances matching the TargetTagKey. By default, on Linux servers, certificates are stored in /etc/ssl/certs and /etc/ssl/private, though these paths can be customized in the Systems Manager document.
  3. After successfully running this Systems Manager document, the Step Functions workflow then advances to its next state, which triggers another Lambda function named Statuscheck. This function monitors the execution status of the previously initiated Systems Manager document. The Step Functions workflow concludes its execution after it confirms the successful installation of certificates on the targeted EC2 instances.

ACM certificate renewal and export

Figure 5: ACM certificate and renewal process

Figure 5: ACM certificate and renewal process

When a certificate is within 60 days of expiring, ACM automatically begins the renewal process. When ACM successfully completes a certificate renewal, it generates an
event in EventBridge as shown in the following example:


{
	"version": "0",
	"id": "id", 
	"detail-type": "ACM Certificate Available",
	"source": "aws.acm",
	"account": "account",
	"time": "2019-12-22T18:43:48Z",
	"region": "region",
	"resources": [
	"arn:aws:acm:region:account:certificate/certificate_ID"
	],
	"detail": 
	{
		"Action" : "RENEWAL",
		"CertificateType" : "AMAZON_ISSUED”, 
		"CommonName": "", 
		"DomainValidationMethod" : "DNS", 
		"CertificateCreatedDate" : "2025-05-22T18:43:48Z",
		"CertificateExpirationDate" : "2026-06-23T18:43:48Z",
		"DaysToExpiry" : 395,
		"InUse" : “TRUE”, 
		"Exported" : “TRUE”, 
		}
	}

The workflow illustrated in Figure 5 showcases an automated system for exporting existing public ACM certificates using an API-driven process and deploying them to downstream systems.

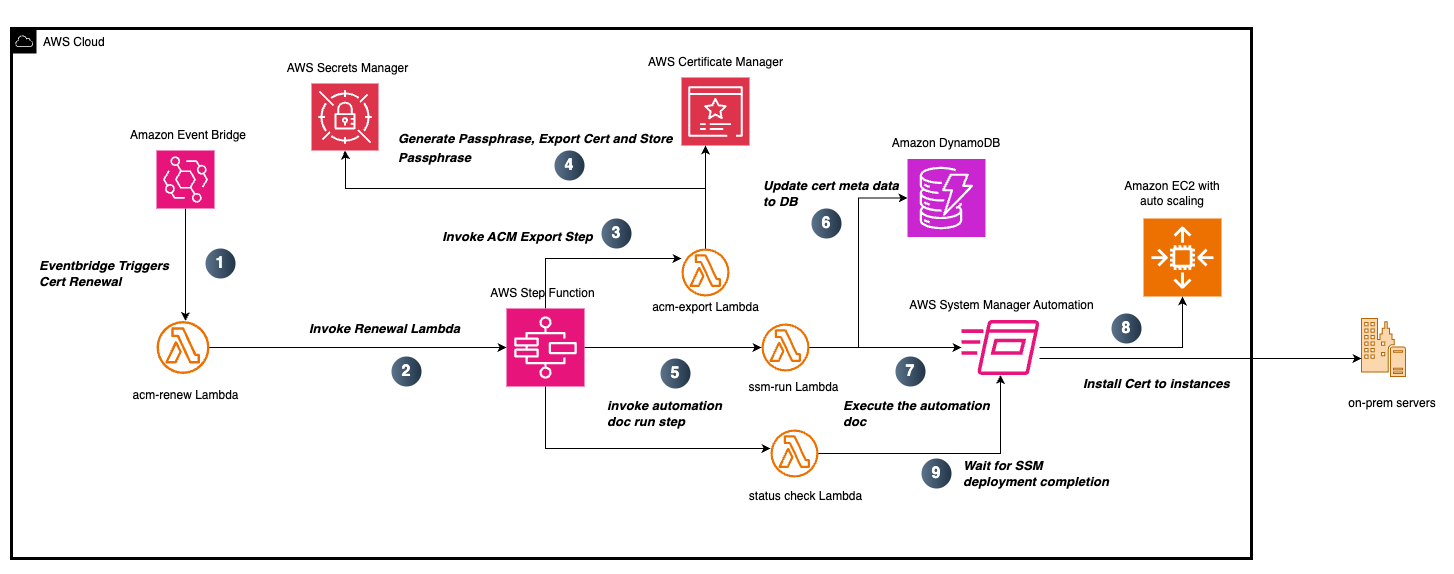
  1. The solution uses an EventBridge rule that watches for certificate renewal notifications and triggers the acm-renew Lambda function in response. The function begins its execution by receiving the certificate ARN from the ACM event. Using this ARN as a lookup key, it queries a DynamoDB table to retrieve the associated certificate metadata. From this query, it extracts essential certificate details including the Certificate Name and the TargetTag Key-Value pairs that identify which resources need the updated certificate. These details are needed for the subsequent certificate deployment process and help make sure that the updates are applied to the correct systems.
  2. This information is then formatted into a payload and used to trigger a Step Functions workflow. This Step Functions workflow follows the same process described in the ACM Certificate Export section.
  3. Steps 3 through 9 follow the process described in the ACM Certificate Export section. Upon successful completion of step 9, the Step Functions workflow concludes its execution. At this point, the renewed public certificate has been successfully installed on the targeted EC2 instances, completing the automated certificate export and installation process.

Detailed instructions for downloading the solution, executing it, validating the certificate export, and deploying it to your AWS account are available on GitHub.

Pricing and availability

ACM exportable public certificates are available in AWS commercial Regions, AWS GovCloud (US) Regions, and China Regions and follow a pay-as-you go pricing model, with no upfront commitments. You pay only for the certificates you export. Public certificates for AWS Services integrated with ACM such as ELB, CloudFront, and API Gateway remain available at no additional cost. For detailed pricing, see AWS Certificate Manager pricing.

Conclusion

The ACM exportable public certificates capability empowers customers to secure diverse workloads with a unified, managed certificate solution. By enabling certificate exports for EC2, containers, on-premises servers and other cloud providers, ACM simplifies TLS management, while offering centralized control, automated renewals and cost-effective pricing. Get started today by exploring this feature in the ACM console and streamline your certificate management workflows.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Pravin Nair

Pravin Nair

Pravin is a Sr. Security Solutions Architect in Data Protection and Privacy. He helps customers build secure, scalable solutions that support their business needs. He has a background in encryption at rest and in transit, infrastructure security, and privacy.

Santosh Vallurupalli

Santosh Vallurupalli

Santosh is a Sr. Solutions Architect at AWS. Santosh specializes in networking, containers, and migrations and enjoys helping customers in their journey of cloud adoption and building cloud-focused solutions for challenging issues. When not working, he likes traveling, watching Formula1, and watching “The Office” in repeat mode.

Chandan Kundapur

Chandan Kundapur

Chandan is a Principal Technical Product Manager on the AWS Certificate Manager (ACM) team. With close to 20 years of cybersecurity experience, he has a passion for driving the ACM team’s product strategy to help AWS customers identify and secure their resources and endpoints with public and private certificates.

Build the highest resilience apps with multi-Region strong consistency in Amazon DynamoDB global tables

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/build-the-highest-resilience-apps-with-multi-region-strong-consistency-in-amazon-dynamodb-global-tables/

While tens of thousands of customers are successfully using Amazon DynamoDB global tables with eventual consistency, we’re seeing emerging needs for even stronger resilience. Many organizations find that the DynamoDB multi-Availability Zone architecture and eventually consistent global tables meet their requirements, but critical applications like payment processing systems and financial services demand more.

For these applications, customers require a zero Recovery Point Objective (RPO) during rare Region-wide events, meaning you can direct your app to read the latest data from any Region. Your multi-Region applications always need to access the same data regardless of location.

Starting today, you can use a new Amazon DynamoDB global tables capability that provides multi-Region strong consistency (MRSC), enabling zero RPO. This capability, first announced as a preview at AWS re:Invent 2024, simplifies building highly resilient global applications.

Here’s how you can enable MRSC starting with an existing empty DynamoDB table:

With MRSC, DynamoDB now offers you the highest level of resilience for your applications. If application processing is interrupted in a Region, you can redirect traffic to another Region containing a MRSC replica and know that you’ll be processing the latest data.

Getting started
Let me walk you through how you can use this new capability.

To start using MRSC, I need to create a global table from an existing DynamoDB table that doesn’t contain any data. I navigate to my existing table, select the Global tables tab and select Create replica.

The MRSC availability architecture requires three AWS Regions. I can configure MRSC with either three full replicas or with two replicas and a witness. A witness contains only replicated change data to provide the required availability without maintaining a full copy of my table data.

The following screenshot shows how I configure MRSC with two replicas and a witness. To configure MRSC with three full replicas instead, I can clear Configure Region 2 as Witness.

If I need to update my existing table programmatically, I can use the Amazon Q CLI to generate the required command with the following prompt:

> Hey Q! Update my existing DynamoDB table called "demo-mrsc" in us-east-1 with multi-Region strong consistency across us-east-2 with witness in us-west-2 Regions

Shortly after, Q CLI will respond back with following command:

> To update your DynamoDB table with multi-Region strong consistency, you'll need to use the update-table command with the appropriate parameters. Here's how you would do it:

aws dynamodb update-table \ 
    --table-name demo-mrsc \ 
    --replica-updates '[{"Create": {"RegionName": "us-east-2"}}]' \ 
    --global-table-witness-updates '[{"Create": {"RegionName": "us-west-2"}}]' \ 
    --multi-region-consistency STRONG \ 
    --region us-east-1

After it’s finished processing, I can check the status of my MRSC global table. I can see I have a witness configured for my DynamoDB global table. A witness reduces costs while still providing the resilience benefits of multi-Region strong consistency.

Then, in my application, I can use ConsistentRead to read data with strong consistency. Here’s a Python example:

import boto3

# Configure the DynamoDB client for your region
dynamodb = boto3.resource('dynamodb', region_name='us-east-2')
table = dynamodb.Table('demo-mrsc')

pk_id = "demo#test123"

# Read with strong consistency across regions
response = table.get_item(
    Key={
        'PK': pk_id
    },
    ConsistentRead=True
)

print(response)

For operations that require the strongest resilience, I can use ConsistentRead=True. For less critical operations where eventual consistency is acceptable, I can omit this parameter to improve performance and reduce costs.

Additional things to know
Here are a couple of things to note:

  • Availability – The Amazon DynamoDB multi-Region strong consistency capability is available in following AWS Regions: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Osaka, Seoul, Tokyo), and Europe (Frankfurt, Ireland, London, Paris)
  • Pricing – Multi-Region strong consistency pricing follows the existing global tables pricing structure. DynamoDB recently reduced global tables pricing by up to 67 percent, making this highly resilient architecture more affordable than ever. Visit Amazon DynamoDB lowers pricing for on-demand throughput and global tables in the AWS Database Blog to learn more.

Learn more about how you can achieve the highest level of application resilience, enable your applications to be always available and always read the latest data regardless of the Region by visiting Amazon DynamoDB global tables.

Happy building!

— Donnie


Amazon Redshift Python user-defined functions will reach end of support after June 30, 2026

Post Syndicated from Raks Khare original https://aws.amazon.com/blogs/big-data/amazon-redshift-python-user-defined-functions-will-reach-end-of-support-after-june-30-2026/

The Amazon Redshift integration with AWS Lambda provides the capability to create Amazon Redshift Lambda user-defined functions (UDFs). This capability delivers flexibility, enhanced integrations, and security for functions defined in Lambda that can be run through SQL queries. Amazon Redshift Lambda UDFs offer many advantages:

  • Enhanced integration – You can connect to external services or APIs from within your UDF logic, enabling richer data enrichment and operational workflows.
  • Multiple Python runtimes – Lambda UDFs benefit from Lambda function support for multiple Python runtimes depending on specific use cases. In addition, the new versions and security patches are available within a month of their official release.
  • Independent scaling – Lambda UDFs use Lambda compute resources, so heavy compute or memory-intensive tasks don’t impact query performance or resource concurrency within Amazon Redshift.
  • Isolation and security – You can isolate custom code execution in a separate service boundary. This simplifies maintenance, monitoring, budgeting, and permission management.

Because Lambda UDFs provide these significant advantages in integration, flexibility, scalability, and security, we will be ending support for Python UDFs in Amazon Redshift. We recommend that you migrate your existing Python UDFs to Lambda UDFs by June 30, 2026.

  • October 30, 2025 – Creation of new Python UDFs will no longer be supported (existing functions can still be invoked)
  • June 30, 2026 – Execution of existing Python UDFs will be suspended

In this post, we walk you through how to migrate your existing Python UDFs to Lambda UDFs, set up monitoring and cost evaluations, and review key considerations for a smooth transition.

Solution overview

You can create UDFs for tasks such as tokenization, encryption and decryption, or data science functionality like the Levenshtein distance calculation. For this post, we provide examples for customers who have Python UDFs in place, demonstrating how to replace them with Lambda UDFs.

The Levenshtein function, also known as the Levenshtein distance or edit distance, is a string metric used to measure the difference between two sequences of characters. Although this functionality was previously implemented using Python UDFs using the Python library in Amazon Redshift, Lambda provides a more efficient and scalable solution. This post demonstrates how to migrate from Python UDFs to Lambda UDFs for calculating Levenshtein distances.

Prerequisites

You must have the following:

Prepare the data

To set up our use case, complete the following steps:

  1. On the Amazon Redshift console, choose Query editor v2 under Explorer in the navigation pane.
  2. Connect to your Redshift data warehouse.
  3. Create a table and load data. The following query loads 30,000,000 rows in the customer table:
DROP TABLE IF EXISTS customer;
CREATE TABLE customer
(
c_customer_sk int4 not null ,
c_customer_id char(16) not null ,
c_current_cdemo_sk int4 ,
c_current_hdemo_sk int4 ,
c_current_addr_sk int4 ,
c_first_shipto_date_sk int4 ,
c_first_sales_date_sk int4 ,
c_salutation char(10) ,
c_first_name char(20) ,
c_last_name char(30) ,
c_preferred_cust_flag char(1) ,
c_birth_day int4 ,
c_birth_month int4 ,
c_birth_year int4 ,
c_birth_country varchar(20) ,
c_login char(13) ,
c_email_address char(50) ,
c_last_review_date_sk int4 ,
primary key (c_customer_sk)
) distkey(c_customer_sk);

COPY customer from 's3://redshift-downloads/TPC-DS/2.13/3TB/customer/'
IAM_ROLE default gzip delimiter '|' EMPTYASNULL REGION 'us-east-1';

Identify existing Python UDFs

Run the following script to list existing Python UDFs:

SELECT 
    p.proname, 
    p.pronargs, 
    t.typname, 
    n.nspname, 
    l.lanname, 
    pg_get_functiondef(p.oid) 
FROM 
    pg_proc p, 
    pg_language l, 
    pg_type t, 
    pg_namespace n
WHERE 
    p.prolang = l.oid
    and p.prorettype = t.oid
    and l.lanname = 'plpythonu'
    and p.pronamespace = n.oid
    and nspname not in ('pg_catalog', 'information_schema')
ORDER BY 
    proname;

The following is our existing Python UDF definition for Levenshtein distance:

create or replace function fn_levenshtein_distance(a varchar, b varchar) returns integer as
$$

def levenshtein_distance(a, len_a, b, len_b):
    d = [[0] * (len_b + 1) for i in range(len_a + 1)]  

    for i in range(1, len_a + 1):
        d[i][0] = i

    for j in range(1, len_b + 1):
        d[0][j] = j
    
    for j in range(1, len_b + 1):
        for i in range(1, len_a + 1):
            if a[i - 1] == b[j - 1]:
                cost = 0
            else:
                cost = 1
            d[i][j] = min(d[i - 1][j] + 1,      # deletion
                          d[i][j - 1] + 1,      # insertion
                          d[i - 1][j - 1] + cost) # substitution   

    return d[len_a][len_b]

def distance(a, b):
    len_a, len_b = len(a), len(b)
    if len_a == len_b:
        return 0
    elif len_a == 0:
        return len_b
    elif len_b == 0:
        return len_a
    else:
        return levenshtein_distance(a, len_a, b, len_b)

return distance(a, b)
$$ immutable;

Convert the Python UDF function to a Lambda UDF

You can simplify converting your Python UDF to a Lambda UDF using Amazon Q Developer, a generative AI-powered assistant. It handles code transformation, packaging, and integration logic, accelerating migration and improving scalability. Integrated with popular developer tools like VS Code, JetBrains, and others, Amazon Q streamlines workflows so teams can modernize analytics using serverless architectures with minimal effort.

Amazon Q Developer code suggestions are based on large language models (LLMs) trained on billions of lines of code, including open source and Amazon code. Always review a code suggestion before accepting it, and you might need to edit it to make sure that it does exactly what you intended.

Convert @python-udf.py Redshift Python UDF to Redshift Lambda UDF which batch processes data in the arguments array in a loop and returns json dump at the end. Refer to @lambda-context.py for reference and additional guidance on Lambda UDF.

Create a Lambda function

Complete the following steps to create a Lambda function:

  1. On the Lambda console, choose Functions in the navigation pane.
  2. Choose Create function.
  3. Choose Author from scratch.
  4. For Function name, enter a custom name (for example, levenshtein_distance_func).
  5. For Runtime, choose your code environment. (The examples in this post are compatible with Python 3.12.)
  6. For Architecture, select your system architecture. (The examples in this post are compatible with x86_64.)

  1. For Execution role, select Create a new role with basic Lambda permissions.

  1. Choose Create function.
  2. Choose Code and add the following code:
import json

def lambda_handler(event, context):
    t1 = event['arguments']
    resp = [None]*len(t1)

    for i, x in enumerate(t1):
        if x[0] is not None and x[1] is not None:
            resp[i] = distance(x[0], x[1])

    ret = dict()
    ret['results'] = resp
    return json.dumps(ret)

def levenshtein_distance(a, len_a, b, len_b):
    d = [[0] * (len_b + 1) for i in range(len_a + 1)]  

    for i in range(1, len_a + 1):
        d[i][0] = i

    for j in range(1, len_b + 1):
        d[0][j] = j
    
    for j in range(1, len_b + 1):
        for i in range(1, len_a + 1):
            if a[i - 1] == b[j - 1]:
                cost = 0
            else:
                cost = 1
            d[i][j] = min(d[i - 1][j] + 1,      # deletion
                          d[i][j - 1] + 1,      # insertion
                          d[i - 1][j - 1] + cost) # substitution   

    return d[len_a][len_b]

def distance(a, b):
    len_a, len_b = len(a), len(b)
    if len_a == len_b and a == b:
        return 0
    elif len_a == 0:
        return len_b
    elif len_b == 0:
        return len_a
    else:
        return levenshtein_distance(a, len_a, b, len_b)
  1. Choose configuration and update Timeout to 1 minute.

You can modify memory to optimize performance. To learn more, see Optimizing Levenshtein User-Defined Function in Amazon Redshift.

Create an Amazon Redshift IAM role

To allow your Amazon Redshift cluster to invoke the Lambda function, you must set up proper IAM permissions. Complete the following steps:

  1. Identify the IAM role associated with your Amazon Redshift cluster. If you don’t have one, create a new IAM role for Amazon Redshift.
  2. Add the following IAM policy to this role, providing your AWS Region and AWS account number:
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": "lambda:InvokeFunction",
"Resource": "arn:aws:lambda:<REGION>:<AWS account>:function:levenshtein_distance_func"
}
]
}

Create a Lambda UDF

Run following script to create your Lambda UDF:

CREATE or REPLACE EXTERNAL FUNCTION 
fn_lambda_levenshtein_distance(a varchar, b varchar) returns int
lambda 'levenshtein_distance_func' IAM_ROLE default 
STABLE
;

Test the solution

To test the solution, run the following script using the Python UDF:

SELECT c_customer_sk, c_customer_id, fn_levenshtein_distance(c_first_name, c_last_name) as distance
FROM customer
WHERE c_customer_sk in (1,2,3,4,5,31);

The following table shows our output.

Run the same script using the Lambda UDF:

SELECT c_customer_sk, c_customer_id, fn_lambda_levenshtein_distance(c_first_name, c_last_name) as distance
FROM customer
WHERE c_customer_sk in (1,2,3,4,5,31);

The results of both UDFs match.

Replace the Python UDF with the Lambda UDF

You can use the following steps in preproduction for testing:

  1. Revoke access for the Python UDF:
REVOKE execute on function fn_levenshtein_distance(varchar, varchar) from <group_name> or <role_name>
  1. Grant access to the Lambda UDF:
grant execute on function fn_lambda_levenshtein_distance(varchar, varchar) to <group_name> or <role_name>
  1. After full testing of the Lambda UDF has been performed, you can drop the Python UDF.
  2. Rename the Lambda UDF fn_lambda_levenshtein_distance to fn_levenshtein_distance so the end-user and application code doesn’t need to change:
ALTER FUNCTION fn_lambda_levenshtein_distance(varchar, varchar)
     RENAME TO fn_levenshtein_distance;
  1. Validate with the following query:
SELECT c_customer_sk, c_customer_id, fn_levenshtein_distance(c_first_name, c_last_name) as distance
FROM customer
WHERE c_customer_sk in (1,2,3,4,5,31);

Cost evaluation

To evaluate the cost of the Lambda UDF, complete the following steps:

  1. Run the following script to create a table using a SELECT query, which uses the Lambda UDF:
DROP TABLE IF EXISTS customer_lambda;
CREATE TABLE customer_lambda as 
SELECT c_customer_sk, c_customer_id, fn_levenshtein_distance(c_first_name, c_last_name) as distance
FROM customer;

You can inspect the query logs using CloudWatch Log Insights.

  1. On the CloudWatch console, choose Logs in the navigation pane, then choose Log Insights.
  2. Filter by the Lambda UDF and use the following query to identify the number of Lambda invocations.
fields @timestamp, @message, @logStream, @log
| filter @message like /^REPORT/
| sort @timestamp desc
| limit 10000

  1. Use following query to find the cost of the Lambda UDF for the specific duration you selected:
parse @message /Duration:\s*(?<@duration_ms>\d+\.\d+)\s*ms\s*Billed\s*Duration:\s*(?<@billed_duration_ms>\d+)\s*ms\s*Memory\s*Size:\s*(?<@memory_size_mb>\d+)\s*MB/
| filter @message like /REPORT RequestId/
| stats sum(@billed_duration_ms * @memory_size_mb * 1.6279296875e-11 + 2.0e-7) as @cost_dollars_total

For this example, we used the us-east-1 Region using ARM-based instances. For more details on Lambda pricing by Region and the Free Tier limit, see AWS Lambda pricing.

  1. Choose Summarize results.

The cost of this Lambda UDF invocation was $0.02329 for 30 million rows.

Monitor Lambda UDFs

Monitoring Lambda UDFs involves tracking both the Lambda function’s performance and the impact on the Redshift query execution. Because UDFs execute externally, a dual approach is necessary.

CloudWatch metrics and logs for Lambda functions

CloudWatch provides comprehensive monitoring for Lambda functions, such as the following key metrics:

  • Invocations – Tracks the number of times the Lambda function is called, indicating UDF usage frequency
  • Duration – Measures execution time, helping identify performance bottlenecks
  • Errors – Counts failed invocations, which is critical for detecting issues in UDF logic
  • Throttles – Indicates when Lambda limits invocations due to concurrency caps, which can delay query results
  • Logs – CloudWatch Logs capture detailed execution output, including errors and custom log messages, aiding in debugging
  • Alarms – Configures alarms for high error rates (for example, Errors > 0) or excessive duration (for example, Duration > 1 second) to receive proactive notifications

Redshift query performance

Within Amazon Redshift, system views provide comprehensive insights into Lambda UDF performance and errors:

  • SYS_QUERY_HISTORY – Identifies queries that have called your Lambda UDFs by filtering with the UDF name in the query_text column. This helps track usage patterns and execution frequency.
  • SYS_QUERY_DETAIL – Provides granular execution metrics for queries involving Lambda UDFs, helping identify performance bottlenecks at the step level.
  • Performance aggregation – Generates summary reports of Lambda UDF performance metrics, including execution count, average duration, and maximum duration to track performance trends over time.

The following table summarizes the monitoring tools available.

Monitoring Tool Purpose Key Metrics/Views
CloudWatch Metrics Track Lambda function performance Invocations, Duration, Errors, Throttles
CloudWatch Logs Debug Lambda execution issues Error messages, custom logs
SYS_QUERY_HISTORY Track Lambda UDF usage patterns Query execution times, status, user information, query text
SYS_QUERY_DETAIL Analyze Lambda UDF performance Step-level execution details, resource utilization, query plan information
Performance Summary Reports Track UDF performance trends Execution count, average/maximum duration, total elapsed time

Monitoring approach for Lambda UDFs in Amazon Redshift

For analyzing individual queries, you can use the following code to track how your Lambda UDFs are being used across your organization:

SELECT * FROM sys_query_history
WHERE query_text LIKE '%your_lambda_udf_name%'
ORDER BY start_time DESC
LIMIT 20;

This helps you do the following:

  • Identify frequent users
  • Monitor execution patterns
  • Track usage trends
  • Detect unauthorized access

You can also create comprehensive monitoring by using query history to monitor performance metrics at the user level:

SELECT 
    usename,
    DATE_TRUNC('day', start_time) as day,
    COUNT(*) as query_count,
    AVG(DATEDIFF(microsecond, start_time, end_time))/1000000.0 as avg_duration_seconds,
    MAX(DATEDIFF(microsecond, start_time, end_time))/1000000.0 as max_duration_seconds
FROM sys_query_history q
JOIN pg_user u ON q.user_id = u.usesysid
WHERE query_text LIKE '%your_lambda_udf_name%'
AND user_id > 1
GROUP BY usename, day
ORDER BY usename, query_count DESC;

Additionally, you can generate weekly performance reports using the following aggregation query:

SELECT 
    'your_lambda_udf_name' AS function_name,
    COUNT(DISTINCT q.query_id) AS execution_count,
    AVG(DATEDIFF(millisecond, q.start_time, q.end_time)) AS avg_duration_ms,
    MAX(DATEDIFF(millisecond, q.start_time, q.end_time)) AS max_duration_ms,
    SUM(q.elapsed_time) / 1000000 AS total_elapsed_time_sec
FROM 
    sys_query_history q
WHERE 
    q.query_text LIKE '%your_lambda_udf_name%'
GROUP BY 
    function_name
ORDER BY 
    execution_count DESC;

Considerations

To maximize the benefits of Lambda UDFs, consider the following aspects to optimize performance, provide reliability, secure data, and manage costs. If you have Python UDFs that don’t use Python libraries, consider whether they are candidates to convert to SQL UDFs.

The following are key performance considerations:

  • Batching – Amazon Redshift batches multiple rows into a single Lambda invocation to reduce call frequency, improving efficiency. Make sure the Lambda function handles batched inputs efficiently. For more details, see Accessing external components using Amazon Redshift Lambda UDFs.
  • Parallel invocations – Redshift cluster slices invoke Lambda functions in parallel, enhancing performance for large datasets. Design functions to support concurrent executions.
  • Cold starts – Lambda functions might experience cold start delays, particularly if infrequently used. Languages like Python or Node.js typically have faster startup times than Java, reducing latency.
  • Function optimization – Optimize Lambda code for quick execution, minimizing resource usage and latency. For example, avoid unnecessary computations or external API calls.

Consider the following error handling methods:

  • Robust lambda logic – Implement comprehensive error handling in the Lambda function to manage exceptions gracefully. Return clear error messages in the JSON response, as specified in the Amazon Redshift-Lambda interface. For more details, see Scalar Lambda UDFs.
  • Error propagation – Lambda errors can cause Redshift query failures. Monitor SYS_QUERY_HISTORY for query-level issues and CloudWatch Logs for detailed Lambda errors.
  • JSON interface – The Lambda function must return a JSON object with success, error_msg, num_records, and results fields. Use proper formatting to avoid query disruptions.

Clean up

Complete the following steps to clean up your resources:

  1. Delete the Redshift provisioned or serverless endpoint.
  2. Delete the Lambda function.
  3. Delete the IAM roles you created.

Conclusion

Lambda UDFs unlock a new level of flexibility, performance, and maintainability for extending Amazon Redshift. By decoupling custom logic from the warehouse engine, teams can scale independently, adopt modern runtimes, and integrate external systems.

If you’re currently using Python UDFs in Amazon Redshift, it’s time to explore the benefits of migrating to Lambda UDFs. With the generative AI capabilities of Amazon Q Developer, you can automate much of this transformation and accelerate your modernization journey. To learn more, refer to the Lambda UDF examples GitHub repo and Data Tokenization with Amazon Redshift and Protegrity.


About the authors

Raks KhareRaks Khare is a Senior Analytics Specialist Solutions Architect at AWS based out of Pennsylvania. He helps customers across varying industries and regions architect data analytics solutions at scale on the AWS platform. Outside of work, he likes exploring new travel and food destinations and spending quality time with his family.

Ritesh Kumar Sinha is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.
Yanzhu Ji is a Product Manager in the Amazon Redshift team. She has experience in product vision and strategy in industry-leading data products and platforms. She has outstanding skill in building substantial software products using web development, system design, database, and distributed programming techniques. In her personal life, Yanzhu likes painting, photography, and playing tennis.
Harshida Patel is a Analytics Specialist Principal Solutions Architect, with AWS.

New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c8gn-instances-powered-by-aws-graviton4-offering-up-to-600gbps-network-bandwidth/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C8gn network optimized instances powered by AWS Graviton4 processors and the latest 6th generation AWS Nitro Card. EC2 C8gn instances deliver up to 600Gbps network bandwidth, the highest bandwidth among EC2 network optimized instances.

You can use C8gn instances to run the most demanding network intensive workloads, such as security and network virtual appliances (virtual firewalls, routers, load balancers, proxy servers, DDoS appliances), data analytics, and tightly-coupled cluster computing jobs.

EC2 C8gn instances specifications
C8gn instances provide up to 192 vCPUs and 384 GiB memory, and offer up to 30 percent higher compute performance compared Graviton3-based EC2 C7gn instances.

Here are the specs for C8gn instances:

Instance Name vCPUs Memory (GiB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
c8gn.medium 1 2 Up to 25 Up to 10
c8gn.large 2 4 Up to 30 Up to 10
c8gn.xlarge 4 8 Up to 40 Up to 10
c8gn.2xlarge 8 16 Up to 50 Up to 10
c8gn.4xlarge 16 32 50 10
c8gn.8xlarge 32 64 100 20
c8gn.12xlarge 48 96 150 30
c8gn.16xlarge 64 128 200 40
c8gn.24xlarge 96 192 300 60
c8gn.metal-24xl 96 192 300 60
c8gn.48xlarge 192 384 600 60
c8gn.metal-48xl 192 384 600 60

You can launch C8gn instances through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs.

If you’re using C7gn instances now, you will have straightforward experience migrating network intensive workloads to C8gn instances because the new instances offer similar vCPU and memory ratios. To learn more, check out the collection of Graviton resources to help you start migrating your applications to Graviton instance types.

You can also visit the Level up your compute with AWS Graviton page to begin your Graviton adoption journey.

Now available
Amazon EC2 C8gn instances are available today in US East (N. Virginia) and US West (Oregon) Regions. Two metal instance sizes are only available in US East (N. Virginia) Region. These instances can be purchased as On-Demand, Savings Plan, Spot instances, or as Dedicated instances and Dedicated hosts.

Give C8gn instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 C8g instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

[$] Fedora’s i686 support gets a reprieve

Post Syndicated from jzb original https://lwn.net/Articles/1026917/

A change
proposal
to end support for 32-bit x86 (i686) applications on the
x86_64 architecture with the Fedora 44 release has been withdrawn
after significant pushback. As proposed, the change could have
had a significant impact on gamers, compiler development, and the Bazzite project, which uses Fedora as a
base for a gaming-focused distribution. While i686 gets a reprieve for
now, the question still lingers: who is going to keep the necessary
i686 packages in working order when few upstream maintainers or
volunteer packagers care about the architecture?

AWS Weekly Roundup: Project Rainier, Amazon CloudWatch investigations, AWS MCP servers, and more (June 30, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-project-rainier-amazon-cloudwatch-investigations-aws-mcp-servers-and-more-june-30-2025/

Every time I visit Seattle, the first thing that greets me at the airport is Mount Rainier. Did you know that the most innovative project at Amazon Web Services (AWS) is named after this mountain?

Project Rainier is a new project to create what is expected to be the world’s most powerful computer for training AI models across multiple data centers in the United Stages. Anthropic will develop the advanced versions of its Claude models with five times more computing power than its current largest training cluster.

The key technology powering Project Rainier is AWS custom-designed Trainium2 chips, which are specialized for the immense data processing required to train complex AI models. Thousands of these Trainium2 chips will be connected in a new type of Amazon EC2 UltraServer and EC2 UltraCluster architecture that allows ultra-fast communication and data sharing across the massive system.

Learn about the AWS vertical integration of Project Rainer, where it designs every component of the technology stack from chips to software, allows it to optimize the entire system for maximum efficiency and reliability.

Last week’s launches
Here are some launches that got my attention:

  • Amazon S3 access for Amazon FSx for OpenZFS – You can access and analyze your FSx for OpenZFS file data through Amazon S3 Access Points, enabling seamless integration with AWS AI/ML, and analytics services without moving your data out of the file system. You can treat your FSx for OpenZFS data as if it were stored in S3, making it accessible through the S3 API for various applications including Amazon Bedrock, Amazon SageMaker, AWS Glue, and other S3 based cloud-native applications.
  • Amazon S3 with sort and z-order compaction for Apache Iceberg tables – You can optimize query performance and reduce costs with new sort and z-order compaction. With S3 Tables, sort compaction automatically organizes data files based on defined column orders, while z-order compaction can be enabled through the maintenance API for efficient multicolumn queries.
  • Amazon CloudWatch investigations – You can accelerate your operational troubleshooting in AWS environments using the Amazon CloudWatch AI-powered investigation feature, which helps identify anomalies, surface related signals, and suggest remediation steps. This capability can be initiated through CloudWatch data widgets, multiple AWS consoles, CloudWatch alarm actions, or Amazon Q chat and enables team collaboration and integration with Slack and Microsoft Teams.
  • Amazon Bedrock Guardrails Standard tier – You can enhance your AI content safety measures using the new Standard tier. It offers improved content filtering and topic denial capabilities across up to 60 languages, better detection of variations including typos, and stronger protection against prompt attacks. This feature lets you configure safeguards to block harmful content, prevent model hallucinations, redact personally identifiable information (PII), and verify factual claims through automated reasoning checks.
  • Amazon Route 53 Resolver endpoints for private hosted zone – You can simplify DNS management across AWS and on-premises infrastructure using the new Route 53 DNS delegation feature for private hosted zone subdomains, which works with both inbound and outbound Resolver endpoints. You can delegate subdomain authority between your on-premises infrastructure and Route 53 Resolver cloud service using name server records, eliminating the need for complex conditional forwarding rules.
  • Amazon Q Developer CLI for Java transformation – You can automate and scale Java application upgrades using the new Amazon Q Developer Java transformation command line interface (CLI). This feature perform upgrades from Java versions 8, 11, 17, or 21 to versions 17 or 21 directly from the command line. This tool offers selective transformation options so you can choose specific steps from transformation plans and customize library upgrades.
  • New AWS IoT Device Management managed integrations – You can simplify Internet of Things (IoT) device management across multiple manufacturers and protocols using the new managed integrations feature, which provides a unified interface for controlling devices whether they connect directly, through hubs or third-party clouds. The feature includes pre-built cloud-to-cloud (C2C) connectors, device data model templates, and SDKs that support ZigBee, Z-Wave, and Wi-Fi protocols, while you can still create custom connectors and data models.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Various Model Context Protocol (MCP) servers for AWS services have been released. Here are some tutorials about MCP servers that you might find interesting:

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. If you’re an early-career professional, you can apply to the All Builders Welcome Grant program, which is designed to remove financial barriers and create diverse pathways into cloud technology.
  • AWS NY Summits – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

The collective thoughts of the interwebz