Enhancing Search Relevancy with Cohere Rerank 3.5 and Amazon OpenSearch Service

Post Syndicated from Breanne Warner original https://aws.amazon.com/blogs/big-data/enhancing-search-relevancy-with-cohere-rerank-3-5-and-amazon-opensearch-service/

This post is co-written with Elliott Choi from Cohere.

The ability to quickly access relevant information is a key differentiator in today’s competitive landscape. As user expectations for search accuracy continue to rise, traditional keyword-based search methods often fall short in delivering truly relevant results. In the rapidly evolving landscape of AI-powered search, organizations are looking to integrate large language models (LLMs) and embedding models with Amazon OpenSearch Service. In this blog post, we’ll dive into the various scenarios for how Cohere Rerank 3.5 improves search results for best matching 25 (BM25), a keyword-based algorithm that performs lexical search, in addition to semantic search. We will also cover how businesses can significantly improve user experience, increase engagement, and ultimately drive better search outcomes by implementing a reranking pipeline.

Amazon OpenSearch Service

Amazon OpenSearch Service is a fully managed service that simplifies the deployment, operation, and scaling of OpenSearch in the AWS Cloud to provide powerful search and analytics capabilities. OpenSearch Service offers robust search capabilities, including URI searches for simple queries and request body searches using a domain-specific language for complex queries. It supports advanced features such as result highlighting, flexible pagination, and k-nearest neighbor (k-NN) search for vector and semantic search use cases. The service also provides multiple query languages, including SQL and Piped Processing Language (PPL), along with customizable relevance tuning and machine learning (ML) integration for improved result ranking. These features make OpenSearch Service a versatile solution for implementing sophisticated search functionality, including the search mechanisms used to power generative AI applications.

Overview of traditional lexical search and semantic search using bi-encoders and cross-encoders

Two important techniques for using end-user search queries are lexical search and semantic search. OpenSearch Service natively supports BM25. This method, while effective for keyword searches, lacks the ability to recognize the intent or context behind a query. Lexical search relies on exact keyword matching between the query and documents. For a natural language query searching for “super hero toys,” it retrieves documents containing those exact terms. While this method is fast and works well for queries targeted at specific terms, it fails to capture context and synonyms, potentially missing relevant results that use different words such as “action figures of superheroes.” Bi-encoders are a specific type of embedding model designed to independently encode two pieces of text. Documents are first turned into an embedding or encoded offline and queries are encoded online at search time. In this approach, the query and document encodings are generated with the same embedding algorithm. The query’s encoding is then compared to pre-computed document embeddings. The similarity between query and documents is measured by their relative distances, despite being encoded separately. This allows the system to recognize synonyms and related concepts, such as “action figures” is related to “toys” and “comic book characters” to “super heroes.”

By contrast, processing the same query—”super hero toys”—with cross-encoders involves first retrieving a set of candidate documents using methods such as lexical search or bi-encoders. Each query-document pair is then jointly evaluated by the cross-encoder, which inputs the combined text to deeply model interactions between the query and document. This approach allows the cross-encoder to understand context, disambiguate meanings, and capture nuances by analyzing every word in relation to each other. It also assigns precise relevance scores to each pair, re-ranking the documents so that those most closely matching the user’s intent—specifically about toys depicting superheroes—are prioritized. Therefore, this significantly enhances search relevancy compared to methods that encode queries and documents independently.

It’s important to note that the effectiveness of semantic search, such as two-stage retrieval search pipelines, depend heavily on the quality of the initial retrieval stage. The primary goal of a robust first-stage retrieval is to efficiently recall a subset of potentially relevant documents from a large collection, setting the foundation for more sophisticated ranking in later stages. The quality of the first-stage results directly impacts the performance of subsequent ranking stages. The goal is to maximize recall and capture as many relevant documents as possible because the later ranking stage has no way to recover excluded documents. A poor initial retrieval can limit the effectiveness of even the most sophisticated re-ranking algorithms.

Overview of Cohere Rerank 3.5

Cohere is an AWS third-party model provider partner that provides advanced language AI models, including embeddings, language models, and reranking models. See Cohere Rerank 3.5 now generally available on Amazon Bedrock to learn more about accessing Cohere’s state-of- the-art models using Amazon Bedrock. The Cohere Rerank 3.5 model focuses on enhancing search relevance by reordering initial search results based on deeper semantic understanding of the user query. Rerank 3.5 uses a cross-encoder architecture where the input of the model always consists of a data pair (for example, a query and a document) that is processed jointly by the encoder. The model outputs an ordered list of results, each with an assigned relevance score, as shown in the following GIF.

Cohere Rerank 3.5 with OpenSearch Service search

Many organizations rely on OpenSearch Service for their lexical search needs, benefiting from its robust and scalable infrastructure. When organizations want to enhance their search capabilities to match the sophistication of semantic search, they are challenged with overhauling their existing systems. Often it is a difficult engineering task for teams or may not be feasible. Now through a single Rerank API call in Amazon Bedrock, you can integrate Rerank into existing systems at scale. For financial services firms, this means more accurate matching of complex queries with relevant financial products and information. For e-commerce businesses, they can improve product discovery and recommendations, potentially boosting conversion rates. The ease of integration through a single API call with Amazon OpenSearch enables quick implementation, offering a competitive edge in user experience without significant disruption or resource allocation.

In benchmarks conducted by Cohere, the normalized Discounted Cumulative Gain (nDCG), Cohere Rerank 3.5 improved accuracy when compared to Cohere’s previous Rerank 3 model as well as BM25 and hybrid search across a financial, e-commerce and project management data sets. The nDCG is a metric that’s used to evaluate the quality of a ranking system by assessing how well ranked items align with their actual relevance and prioritizes relevant results at the top. In this study, @10 indicates that the metric was calculated considering only the top 10 items in the ranked list. The nDCG metric is helpful because metrics such as precision, recall, and the F-score measure predictive performance without taking into account the position of ranked results. Whereas the nDCG normalizes scores and discounts relevant results that are returned lower on the list of results. The following figures below shows these performance improvements of Cohere Rerank 3.5 for financial domain as well as e-commerce evaluation consisting of external datasets.

Also, Cohere Rerank 3.5, when integrated with OpenSearch, can significantly enhance existing project management workflows by improving the relevance and accuracy of search results across engineering tickets, issue tracking systems, and open-source repository issues. This enables teams to quickly surface the most pertinent information from their extensive knowledge bases and boosting productivity. The following figure demonstrates the performance improvements of Cohere Rerank 3.5 for project management evaluation.

Combining reranking with BM25 for enterprise search is supported by studies from other organizations. For instance Anthropic, an artificial intelligence startup founded in 2021 that focuses on developing safe and reliable AI systems, conducted a study that found using reranked contextual embedding and contextual BM25 reduced the top-20-chunk retrieval failure rate by 67%, from 5.7% to 1.9%. The combination of BM25’s strength in exact matching with the semantic understanding of reranking models addresses the limitations of each approach when used alone and delivers a more effective search experience for users.

As organizations strive to improve their search capabilities, many find that traditional keyword-based methods such BM25 have limitations in understanding context and user intent. This leads customers to explore hybrid search approaches that combine the strengths of keyword-based algorithms with the semantic understanding of modern AI models. OpenSearch Service 2.11 and later supports the creation of hybrid search pipelines using normalization processors directly within the OpenSearch Service domain. By transitioning to a hybrid search system, organizations can use the precision of BM25 while benefiting from the contextual awareness and relevance ranking capabilities of semantic search.

Cohere Rerank 3.5 acts as a final refinement layer, analyzing the semantic and contextual aspects of both the query and the initial search results. These models excel at understanding nuanced relationships between queries and potential results, considering factors like customer reviews, product images, or detailed descriptions to further refine the top results. This progression from keyword search to semantic understanding, and then applying advanced reranking, allows for a dramatic improvement in search relevance.

How to integrate Cohere Rerank 3.5 with OpenSearch Service

There are several options available to integrate and use Cohere Rerank 3.5 with OpenSearch Service. Teams can use OpenSearch Service ML connectors which facilitate access to models hosted on third-party ML platforms. Every connector is specified by a connector blueprint. The blueprint defines all the parameters that you need to provide when creating a connector.

In addition to the Bedrock Rerank API, teams can use the Amazon SageMaker connector blueprint for Cohere Rerank hosted on Amazon Sagemaker for flexible deployment and fine-tuning of Cohere models. This connector option works with other AWS services for comprehensive ML workflows and allows teams to use the tools built into Amazon SageMaker for model performance monitoring and management. There is also a Cohere native connector option available that provides direct integration with Cohere’s API, offering immediate access to the latest models and is suitable for users with fine-tuned models on Cohere.

See this general reranking pipeline guide for OpenSearch Service 2.12 and later or this tutorial to configure a search pipeline that uses Cohere Rerank 3.5 to improve a first-stage retrieval system that can run on the native OpenSearch Service vector engine.

Conclusion

Integrating Cohere Rerank 3.5 with OpenSearch Service is a powerful way to enhance your search functionality and deliver a more meaningful and relevant search experience for your users. We covered the added benefits a rerank model could bring to various businesses and how a reranker can enhance search. By tapping into the semantic understanding of Cohere’s models, you can surface the most pertinent results, improve user satisfaction, and drive better business outcomes.


About the Authors

Breanne Warner is an Enterprise Solutions Architect at Amazon Web Services supporting healthcare and life science (HCLS) customers. She is passionate about supporting customers to use generative AI on AWS and evangelizing model adoption for 1P and 3P models. Breanne is also on the Women@Amazon board as co-director of Allyship with the goal of fostering inclusive and diverse culture at Amazon. Breanne holds a Bachelor of Science in Computer Engineering from University of Illinois at Urbana Champaign (UIUC).

Karan Singh is a generative AI Specialist for 3P models at AWS where he works with top-tier 3P foundational model providers to define and execute join GTM motions that help customers train, deploy, and scale models to enable transformative business applications and use cases across industry verticals. Karan holds a Bachelor of Science in Electrical and Instrumentation Engineering from Manipal University, a Masters in Science in Electrical Engineering from Northwestern University, and is currently an MBA Candidate at the Haas School of Business at University of California, Berkeley.

Hugo Tse is a Solutions Architect at Amazon Web Services supporting independent software vendors. He strives to help customers use technology to solve challenges and create business opportunities, especially in the domains of generative AI and storage. Hugo holds a Bachelor of Arts in Economics from the University of Chicago and a Master of Science in Information Technology from Arizona State University.

Elliott Choi is a Staff Product Manager at Cohere working on the Search and Retrieval Team. Elliott holds a Bachelor of Engineering and a Bachelor of Arts from the University of Western Ontario.

Introducing the new Amazon Kinesis source connector for Apache Flink

Post Syndicated from Lorenzo Nicora original https://aws.amazon.com/blogs/big-data/introducing-the-new-amazon-kinesis-source-connector-for-apache-flink/

On November 11, 2024, the Apache Flink community released a new version of AWS services connectors, an AWS open source contribution. This new release, version 5.0.0, introduces a new source connector to read data from Amazon Kinesis Data Streams. In this post, we explain how the new features of this connector can improve performance and reliability of your Apache Flink application.

Apache Flink has both a source and sink connector, to read from and write to Kinesis Data Streams. In this post, we focus on the new source connector, because version 5.0.0 does not introduce new functionality for the sink.

Apache Flink is a framework and distributed stream processing engine designed to perform computation at in-memory speed and at any scale. Amazon Managed Service for Apache Flink offers a fully managed, serverless experience to run your Flink applications, implemented in Java, Python or SQL, and using all the APIs available in Flink: SQL, Table, DataStream, and ProcessFunction API.

Apache Flink connectors

Flink supports reading and writing data to external systems, through connectors, which are components that allow your application to interact with stream-storage message brokers, databases, or object stores. Kinesis Data Streams is a popular source and destination for streaming applications. Flink provides both source and sink connectors for Kinesis Data Streams.

The following diagram illustrates a sample architecture.

Role of connectors in a Flink applications

Before proceeding further, it’s important to clarify three terms often used interchangeably in data streaming and in the Apache Flink documentation:

  • Kinesis Data Streams refers to the Amazon service
  • Kinesis source and Kinesis consumer refer to the Apache Flink components, in particular the source connectors, that allows reading data from Kinesis Data Streams
  • In this post, we use the term stream referring to a single Kinesis data stream

Introducing the new Flink Kinesis source connector

The launch of the version 5.0.0 of AWS connectors introduces a new connector for reading events from Kinesis Data Streams. The new connector is called Kinesis Streams Source and supersedes the Kinesis Consumer as the source connector for Kinesis Data Streams.

The new connector introduces several new features and adheres to the new Flink Source interface, and is compatible with Flink 2.x, the first major version release by the Flink community. Flink 2.x introduces a number of breaking changes, including removing the SourceFunction interface used by legacy connectors. The legacy Kinesis Consumer will no longer work with Flink 2.x.

Setting up the connector is slightly different than with the legacy Kinesis connector. Let’s start with the DataStream API.

How to use the new connector with the DataStream API

To add the new connector to your application, you need to update the connector dependency. For the DataStream API, the dependency has changed its name to flink-connector-aws-kinesis-streams.

At the time of writing, the latest connector version is 5.0.0 and it supports the most recent stable Flink versions, 1.19 and 1.20. The connector is also compatible with Flink 2.0, but no connector has been officially released for Flink 2.x yet. Assuming you are using Flink 1.20, the new dependency is the following:

<dependency>
    <groupId>org.apache.flink</groupId>
    <artifactId>flink-connector-aws-kinesis streams</artifactId>
    <version>5.0.0-1.20</version>
</dependency>

The connector uses the new Flink Source interface. This interface implements the new FLIP-27 standard, and replaces the legacy SourceFunction interface that has been deprecated. SourceFunction will be completely removed in Flink 2.x.

In your application, you can now use a fluent and expressive builder interface to instantiate and configure the source. The minimal setup only requires the stream Amazon Resource Name (ARN) and the deserialization schema:

KinesisStreamsSource<String> kdsSource = KinesisStreamsSource.<String>builder()
    .setStreamArn("arn:aws:kinesis:us-east-1:123456789012:stream/test-stream")
    .setDeserializationSchema(new SimpleStringSchema())
    .build();

The new source class is called KinesisStreamSource. Not to be confused with the legacy source, FlinkKinesisConsumer.

You can then add the source to the execution environment using the new fromSource() method. This method requires explicitly specifying the watermark strategy, along with a name for the source:

StreamExecutionEnvironment env = StreamExecutionEnvironment.getExecutionEnvironment();
// ...
DataStream<String> kinesisRecordsWithEventTimeWatermarks = env.fromSource(
    kdsSource,
    WatermarkStrategy.<String>forMonotonousTimestamps()
        .withIdleness(Duration.ofSeconds(1)),
    "Kinesis source");

These few lines of code introduce some of the main changes in the interface of the connector, which we discuss in the following sections.

Stream ARN

You can now define the Kinesis data stream ARN, as opposed to the stream name. This makes it simpler to consume from streams cross-Region and cross-account.

When running in Amazon Managed Service for Apache Flink, you only need to add to the application AWS Identity and Access Management (IAM) role permissions to access the stream. The ARN allows pointing to a stream located in a different AWS Region or account, without assuming roles or passing any external credentials.

Explicit watermark

One of the most important characteristics of the new Source interface is that you have to explicitly define a watermark strategy when you attach the source to the execution environment. If your application only implements processing-time semantics, you can specify WatermarkStrategy.noWatermarks().

This is an improvement in terms of code readability. Looking at the source, you know immediately which type of watermark you have, or if you don’t have any. Previously, many connectors were providing some type of default watermarks that the user could override. However, the default watermark of each connector was slightly different and confusing for the user.

With the new connector, you can achieve the same behavior as the legacy FlinkKinesisConsumer default watermarks, using WatermarkStrategy.forMonotonousTimestamps(), as shown in the previous example. This strategy generates watermarks based on the approximateArrivalTimestamp returned by Kinesis Data Streams. This timestamp corresponds to the time when the record was published to Kinesis Data Streams.

Idleness and watermark alignment

With the watermark strategy, you can additionally define an idleness, which allows the watermark to progress even when some shards of the stream are idle and receiving no records. Refer to Dealing With Idle Sources for more details about idleness and watermark generators.

A feature introduced by the new Source interface, and fully supported by the new Kinesis source, is watermark alignment. Watermark alignment works in the opposite direction of idleness. It slows down consuming from a shard that is progressing faster than others. This is particularly useful when replaying data from a stream, to reduce the volume of data buffered in the application state. Refer to Watermark alignment for more details.

Set up the connector with the Table API and SQL

Assuming you are using Flink 1.20, the dependency containing both Kinesis source and sink for the Table API and SQL is the following (both Flink 1.19 and 1.20 are supported, adjust the version accordingly):

<dependency>
    <groupId>org.apache.flink</groupId>
    <artifactId>flink-connector-kinesis</artifactId>
    <version>5.0.0-1.20</version>
</dependency>

This dependency contains both the new source and the legacy source. Refer to Versioning in case you are planning to use both in the same application.

When defining the source in SQL or the Table API, you use the connector name kinesis, as it was with the legacy source. However, many parameters have changed with the new source:

CREATE TABLE KinesisTable (
    `user_id` BIGINT,
    `item_id` BIGINT,
    `category_id` BIGINT,
    `behavior` STRING,
    `ts` TIMESTAMP(3)
)
PARTITIONED BY (user_id, item_id)
WITH (
    'connector' = 'kinesis',
    'stream.arn' = 'arn:aws:kinesis:us-east-1:012345678901:stream/my-stream-name',
    'aws.region' = 'us-east-1',
    'source.init.position' = 'LATEST',
    'format' = 'csv'
);

A couple of notable connector options changed from the legacy source are:

  • stream.arn specifies the stream ARN, as opposed to the stream name used in the legacy source.
  • init.initpos defines the starting position. This option works similarly to the legacy source, but the option name is different. It was previously scan.stream.initpos.

For the full list of connector options refer to Connector Options.

New features and improvements

In this section, we discuss the most important features introduced by the new connector. These features are available in the DataStream API, and also the Table API and SQL.

Ordering guarantees

The most important improvement introduced by the new connector is about ordering guarantees.

With Kinesis Data Streams, the order of the message is retained per partitionId. This is achieved by putting all records with the same partitionId in the same shard. However, when the stream scales, splitting or merging shards, records with the same partitionId end up in a new shard. Kinesis keeps track of the parent-child lineage when resharding happens.

Stream resharding

One known limitation of the legacy Kinesis source is that it was unable to follow the parent-child shard lineage. As a consequence, ordering could not be guaranteed when resharding happens. The problem was particularly relevant when the application replayed old messages from a stream that had been resharded because ordering would be lost. This also made watermark generation and event-time processing non-deterministic.

With the new connector, ordering is retained also when resharding happens. This is achieved following the parent-child shard lineage, and consuming all records from a parent shard before proceeding with the child shard.

How the connector follows shard lineage

A better default shard assigner

Each Kinesis data stream is comprised of many shards. Also, the Flink source operator runs in multiple parallel subtasks. The shard assigner is the component that decides how to assign the shards of the stream across the source subtasks. The shard assigner’s job is non-trivial, because shard split or merge operations (resharding) might happen when the stream scales up or down.

The new connector comes with a new default assigner, UniformShardAssigner. This assigner maintains uniform distribution of the stream partitionId across parallel subtasks, also when resharding happens. This is achieved by looking at the range of partition keys (HashKeyRange) of each shard.

This shard assigner was already available in the previous connector version, but for backward compatibility, it was not the default and you had to set it up explicitly. This is no longer the case with the new source. The old default shard assigner, the legacy FlinkKinesisConsumer, was evenly distributing shards (not partitionId) across subtasks. In this case, the actual data distribution might become uneven in the case of resharding, because of the combination of open and closed shards in the stream. Refer to Shard Assignment Strategy for more details.

Reduced JAR size

The size of the JAR file has been reduced by 99%, from about 60 MB down to 200 KB. This substantially reduces the size of the fat-JAR of your application using the connector. A smaller JAR can speed up many operations that require redeploying the application.

AWS SDK for Java 2.x

The new connector is based on the newer AWS SDK for Java 2.x, which adds several features and improves support for non-blocking I/O. This makes the connector future-proof because the AWS SDK v1 will reach end-of-support by end of 2025.

AWS SDK built-in retry strategy

The new connector relies on the AWS SDK built-in retry strategy, as opposed to a custom strategy implemented by the legacy connector. Relying on the AWS SDK improves the classification of some errors as retriable or non-retriable.

Removed dependency on the Kinesis Client Library and Kinesis Producer Library

The new connector package no longer includes the Kinesis Client Library (KCL) and Kinesis Producer Library (KPL), contributing to the substantial reduction of the JAR size that we have mentioned.

An implication of this change is that the new connector no longer supports de-aggregation out of the box. Unless you are publishing records to the stream using the KPL and you enabled aggregation, this will not make any difference for you. If your producers use KPL aggregation, you might consider implementing a custom DeserializationSchema to de-aggregate the records in the source.

Migrating from the legacy connector

Flink sources typically save the position in the checkpoint and savepoints, called snapshots in Amazon Managed Service for Apache Flink. When you stop and restart the application, or when you update the application to deploy a change, the default behavior is saving the source position in the snapshot just before stopping the application, and restoring the position when the application restarts. This allows Flink to provide exactly-once guarantees on the source.

However, due to the major changes introduced by the new KinesisSource, the saved state is no longer compatible with the legacy FlinkKinesisConsumer. This means that when you upgrade the source of an existing application, you can’t directly restore the source position from the snapshot.

For this reason, migrating your application to the new source requires some attention. The exact migration process depends on your use case. There are two general scenarios:

  • Your application uses the DataStream API and you are following Flink best practices defining a UID on each operator
  • Your application uses the Table API or SQL, or your application used the DataStream API and you are not defining a UID on each operator

Let’s cover each of these scenarios.

Your application uses the DataStream API and you are defining a UID on each operator

In this case, you might consider selectively resetting the state of the source operator, retaining any other application state. The general approach is as follows:

  1. Update your application dependencies and code, replacing the FlinkKinesisConsumer with the new KinesisSource.
  2. Change the UID of the source operator (use a different string). Leave all other operators’ UIDs This will selectively reset the state of the source while retaining the state of all other operators.
  3. Configure the source starting position using AT_TIMESTAMP and set the timestamp to just before the moment you will deploy the change. See Configuring Starting Position to learn how to set the starting position. We recommend passing the timestamp as a runtime property to make this more flexible. The configured source starting position is used only when the application can’t restore the state from a savepoint (or snapshot). In this case, we are deliberately forcing this, changing the UID of the source operator.
  4. Update the Amazon Managed Service for Apache Flink application, selecting the new JAR containing the modified application. Restart from the latest snapshot (default behavior) and select allowNonRestoredState = true. Without this flag, Flink would prevent restarting the application, not being able to restore the state of the old source that was saved in the snapshot. See Savepointing for more details about allowNonRestoredState.

This approach will cause the reprocessing of some records from the source, and internal state exactly-once consistency can be broken. Carefully evaluate the impact of reprocessing on your application, and the impact of duplicates on the downstream systems.

Your application uses the Table API or SQL, or your application used the DataStream API and you are not defining a UID on each operator

In this case, you can’t selectively reset the state of the source operator.

Why does this happen? When using the Table API or SQL, or the DataStream API without defining the operator’s UID explicitly, Flink automatically generates identifiers for all operators based on the structure of the job graph of your application. These identifiers are used to identify the state of each operator when saved in the snapshots, and to restore it to the correct operator when you restart the application.

Changes to the application might cause changes in the underlying data flow. This changes the auto-generated identifier. If you are using the DataStream API and you are specifying the UID, Flink uses your identifiers instead of the auto-generated identifies, and is able to map back the state to the operator, even when you make changes to the application. This is an intrinsic limitation of Flink, explained in Set UUIDs For All Operators. Enabling allowNonRestoredState does not solve this problem, because Flink is not able to map the state saved in the snapshot with the actual operators, after the changes.

In our migration scenario, the only option is resetting the state of your application. You can achieve this in Amazon Managed Service for Apache Flink by selecting Skip restore from snapshot (SKIP_RESTORE_FROM_SNAPSHOT) when you deploy the change that replaces the source connector.

After the application using the new source is up and running, you can switch back to the default behavior of when restarting the application, using the latest snapshots (RESTORE_FROM_LATEST_SNAPSHOT). This way, no data loss happens when the application is restarted.

Choosing the right connector package and version

The dependency version you need to pick is normally <connector-version>-<flink-version>. For example, the latest Kinesis connector version is 5.0.0. If you are using a Flink runtime version 1.20.x, your dependency for the DataStream API is 5.0.0-1.20.

For the most up-to-date connector versions, see Use Apache Flink connectors with Managed Service for Apache Flink.

Connector artifact

In previous versions of the connector (4.x and before), there were separate packages for the source and sink. This additional level of complexity has been removed with version 5.x.

For your Java application, or Python applications where you package JAR dependencies using Maven, as shown in the Amazon Managed Service for Apache Flink examples GitHub repository, the following dependency contains the new version of both source and sink connectors:

<dependency>
    <groupId>org.apache.flink</groupId>
    <artifactId>flink-connector-aws-kinesis-streams</artifactId>
    <version>5.0.0-1.20</version>
</dependency>

Make sure you’re using the latest available version. At the time of writing, this is 5.0.0. You can verify the available artifact versions in Maven Central. Also, use the correct version depending on your Flink runtime version. The previous example is for Flink 1.20.0.

Connector artifacts for Python application

If you use Python, we recommend packaging JAR dependencies using Maven, as shown in the Amazon Managed Service for Apache Flink examples GitHub repository. However, if you’re passing directly a single JAR to your Amazon Managed Service for Apache Flink application, you need to use the artifact that includes all transitive dependencies. In the case of the new Kinesis source and sink, this is called flink-sql-connector-aws-kinesis-streams. This artifact includes only the new source. Refer to Amazon Kinesis Data Streams SQL Connector for the right package, in case you want to use both the new and the legacy source.

Conclusion

The new Flink Kinesis source connector introduces many new features that improve stability and performance, and prepares your application for Flink 2.x. Support for watermark idleness and alignment is a particularly important feature if your application uses event-time semantics. The ability to retain record ordering improves data consistency, in particular when stream resharding happens, and when you replay old data from a stream that has been reshared.

You should carefully plan the change if you’re migrating your application from the legacy Kinesis source connector, and make sure you follow Flink’s best practices like specifying a UID on all DataStream operators.

You can find a working example of Java DataStream API application using the new connector, in the Amazon Managed Service for Apache Flink samples GitHub repository.

To learn more about the new Flink Kinesis source connector, refer to Amazon Kinesis Data Streams Connector and Amazon Kinesis Data Streams SQL Connector.


About the Author

Lorenzo NicoraLorenzo Nicora works as a Senior Streaming Solutions Architect at AWS, helping customers across EMEA. He has been building cloud-centered, data-intensive systems for over 25 years, working across industries both through consultancies and product companies. He has used open source technologies extensively and contributed to several projects, including Apache Flink.
[$] Emacs code completion can cause compromise

Post Syndicated from daroc original https://lwn.net/Articles/1002046/

Emacs has had a
few bugs related to accidentally
permitting the execution of untrusted code. Unfortunately, it seems as though
another bug of that sort has appeared — and may be harder to patch,
because the problem comes from the way Emacs handles expansion of Lisp macros in
code being analyzed. The
vulnerability is only practically exploitable in a non-default configuration, so
not every Emacs user has something to worry about. The Emacs
developers are reportedly working on a fix, but have not yet shared details
about it. In the meantime, every Emacs version since at least
26.1 (released in May 2018) through the current development version is vulnerable.

Security updates for Wednesday

Post Syndicated from jzb original https://lwn.net/Articles/1002703/

Security updates have been issued by AlmaLinux (libsndfile, php:7.4, python3.11, python3.12, and python36:3.6), Debian (dpdk), Mageia (curl and socat), Oracle (firefox and tuned), Red Hat (bluez, containernetworking-plugins, edk2, edk2:20220126gitbb1bba3d77, edk2:20240524, expat, gstreamer1-plugins-base, gstreamer1-plugins-base and gstreamer1-plugins-good, gstreamer1-plugins-good, kernel, libsndfile, libsndfile:1.0.31, mpg123, mpg123:1.32.9, pam, python3.11-urllib3, skopeo, tuned, unbound, and unbound:1.16.2), SUSE (cloudflared, curl, docker, firefox, gstreamer-plugins-good, kernel, libmozjs-115-0, libmozjs-128-0, libmozjs-78-0, libsoup, ovmf, python-urllib3_1, subversion, thunderbird, and traefik), and Ubuntu (editorconfig-core, libspring-java, linux, linux-aws, linux-aws-6.8, linux-gcp, linux-gcp-6.8, linux-gke,
linux-gkeop, linux-ibm, linux-nvidia, linux-nvidia-6.8,
linux-nvidia-lowlatency, linux-oem-6.8, linux-oracle, linux-oracle-6.8,
linux-raspi, linux, linux-gcp, linux-gcp-5.15, linux-gke, linux-gkeop, linux-ibm,
linux-ibm-5.15, linux-kvm, linux-lowlatency, linux-lowlatency-hwe-5.15,
linux-nvidia, linux-oracle, linux-oracle-5.15, linux-raspi, linux, linux-gcp, linux-gcp-5.4, linux-hwe-5.4, linux-kvm, linux-raspi, linux, linux-lowlatency, linux-oracle, linux-aws, linux-aws-5.15, linux-aws, linux-aws-5.4, linux-bluefield, linux-oracle, linux-oracle-5.4, and linux-oem-6.11).

What’s New in Rapid7 Products & Services: Q4 2024 in Review

Post Syndicated from Margaret Wei original https://blog.rapid7.com/2024/12/18/whats-new-in-rapid7-products-services-q4-2024-in-review/

What’s New in Rapid7 Products & Services: Q4 2024 in Review

This quarter at Rapid7 we continued to make investments across our Command Platform to provide security professionals with a holistic, actionable view of their entire attack surface – from Exposure Management to Detection and Response. Below, we’ve highlighted key releases and updates from the quarter across our products and services, including the new Platform Home Navigation experience, extensibility enhancements to Exposure Command and Surface Command, expanded MXDR support, and 2024 threat landscape trends from Rapid7 Labs.

Accelerate security efficiency and results with Rapid7’s Command Platform

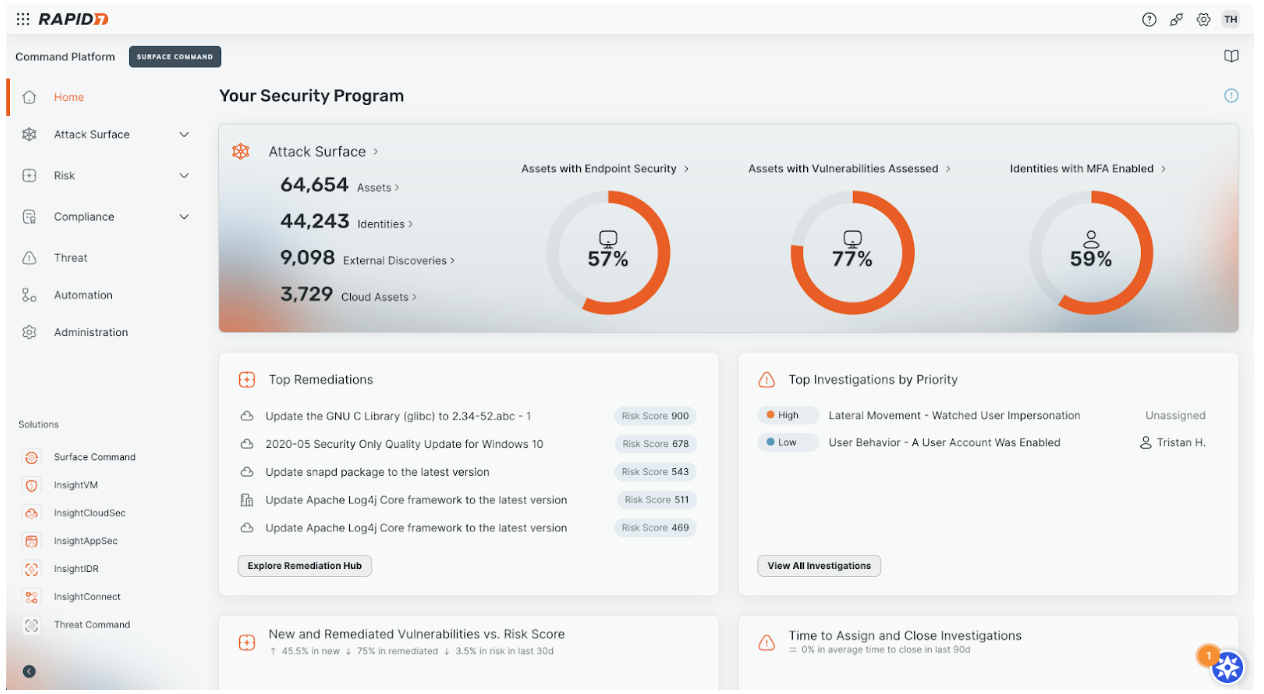
In October, we released our revamped, modernized Command Platform home navigation experience for all users, providing a more cohesive, efficient flow for our users and increased visibility between Rapid7 products and capabilities. Now, viewing security program metrics across your suite of Rapid7 products is easier than ever before—so you can spend less time navigating between products and more time making decisions with easily accessible data.

We’ll be building on this new experience in the coming year to bring iterative updates to the look, feel, and function of the Command Platform—stay tuned for more!

What’s New in Rapid7 Products & Services: Q4 2024 in Review
New Command Platform Home Navigation

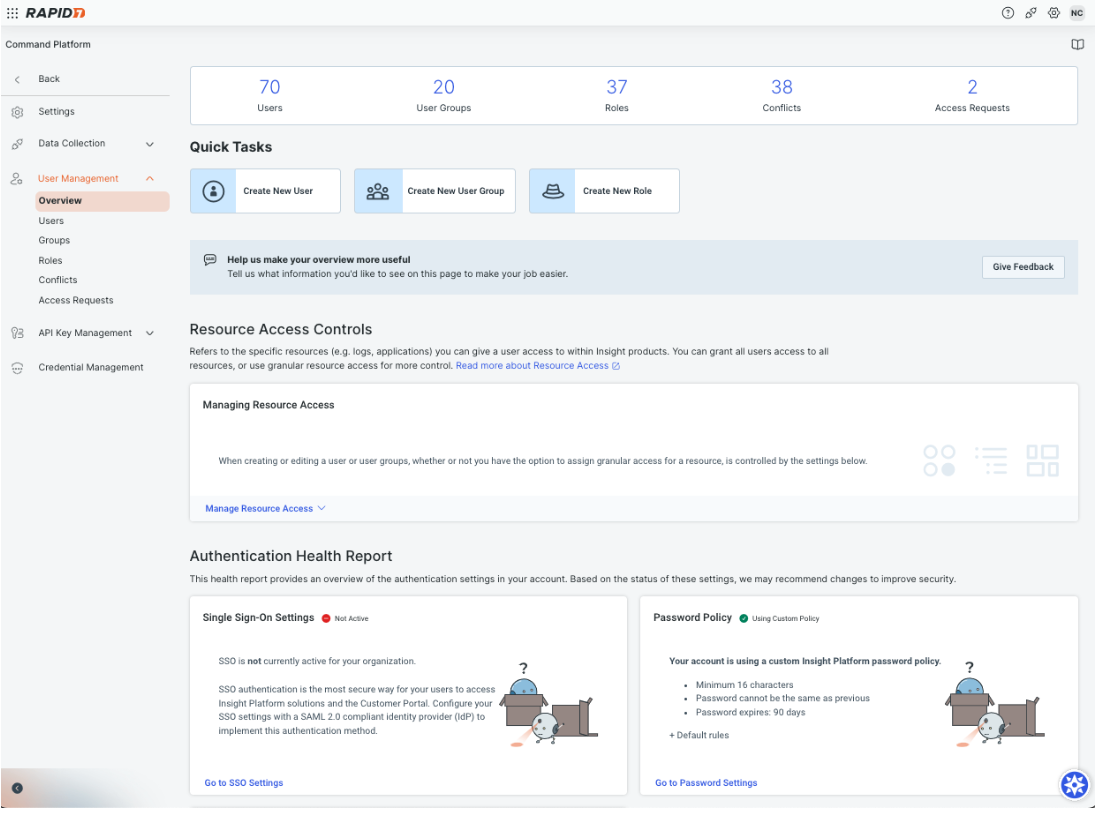
Along with the navigation updates, we’ve made improvements to our user management experience. Now, teams are empowered to better safeguard data and systems with more tailored, role- and responsibility-based user access controls. This enables easier collaboration across your organization while ensuring the appropriate access level for each person.

What’s New in Rapid7 Products & Services: Q4 2024 in Review
Revamped user management experience

Achieve complete attack surface visibility and proactively eliminate exposures from endpoint to cloud

Rapid7 co-launches Resource Control Policies with AWS, Adding Support in Exposure Command and InsightCloudSec

Leading up to Re:Invent, AWS announced a powerful new feature to help organizations enforce least privilege access at scale: Resource Control Policies (RCPs). RCPs are an org-level access control policy that can be used to centrally implement and enforce preventative controls across all AWS resources in your environment.

To support this launch, we expanded our existing cloud identity and entitlement management capabilities to include dedicated, out-of-the-box checks for consistent and secure application of RCPs. Today, both Exposure Command and InsightCloudSec include these checks, enabling organizations to apply RCPs consistently and securely. Learn more here.

Shifting Left to Stay Secure with Exposure Command

Developers are at the forefront of modern cloud environments, making “shift-left” strategies essential for effective security. By addressing risks during development rather than after deployment, teams can eliminate vulnerabilities before they become costly issues.

To support our customers in executing stronger shift-left strategies, Exposure Command now offers more robust Infrastructure-as-Code (IaC) scanning and deeper CI/CD integration with Terraform and CloudFormation support across hundreds of resource types. For development teams, integrations like GitLab, GitHub Actions, AWS CloudFormation, and Azure DevOps bring security checks directly into their workflows, helping to secure code without disrupting productivity.

Streamline Vulnerability Management Across Your Entire Application Inventory with Vulnerability Groupings

Triaging scan results can be one of the most arduous and time-consuming parts of vulnerability management, but it’s also one of the most critical. Teams need to quickly synthesize results to validate exposures, prioritize response, and determine next steps for safeguarding their attack surface.

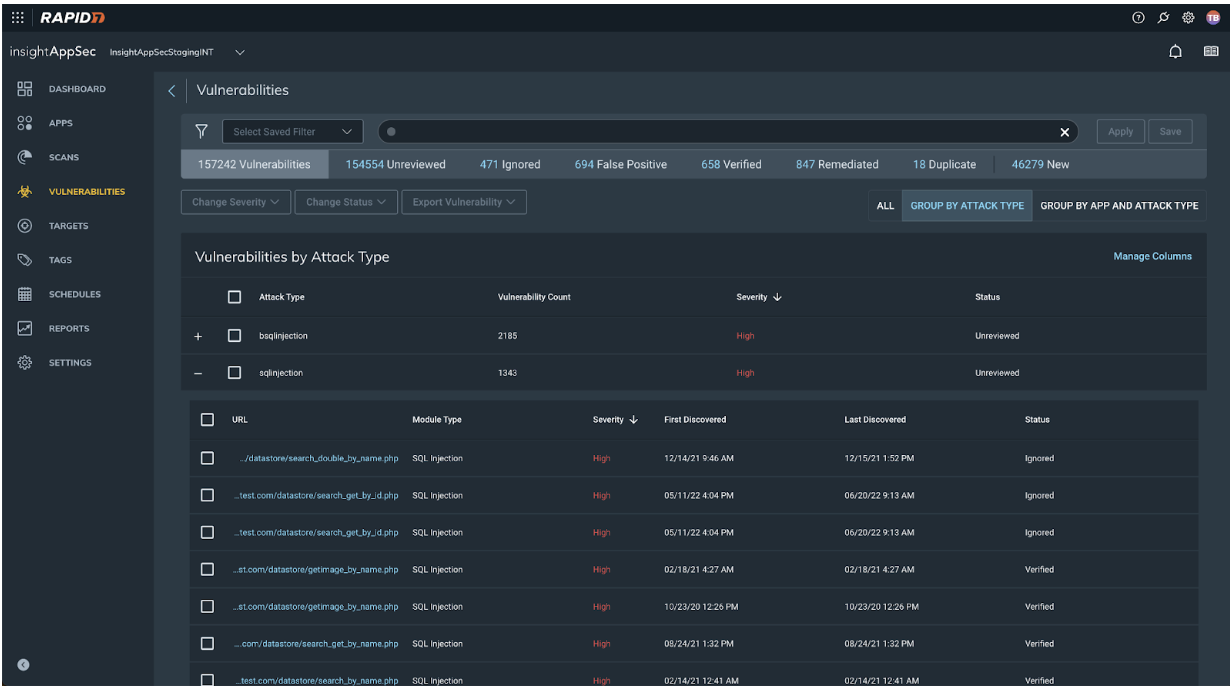
With the recent addition of Application Vulnerability Grouping, InsightAppSec customers can now visualize attacks and assess single applications or their entire application inventory at once, allowing teams to:

  • Visualize exposures with pre-triaged vulnerabilities by app and attack type
  • Identify and focus on threats in key functional areas to simplify vulnerability remediation
  • Manage application-layer risks at scale by updating the status or severity and adding comments to entire groups of vulnerabilities at once
What’s New in Rapid7 Products & Services: Q4 2024 in Review

Explore Exposure Management Use Cases via Guided Product Tours

We’re excited to introduce a new way for you to engage hands-on with core use cases across the Command Platform with our new guided product tours. These tours provide a first-hand, in-depth look at new products and features.

Today, you’ll see tours showcasing how Surface Command can help you map your entire attack surface and identify coverage gaps across your security ecosystem. You’ll also learn how you can prioritize remediation efforts and mobilize teams across your organization with Remediation Hub. Check out the available tours here, and we’ll continue to add more covering use cases across the Command Platform in the future.

Gain Insights from Products Across Your Environment Faster with Self-Service Surface Command Connector

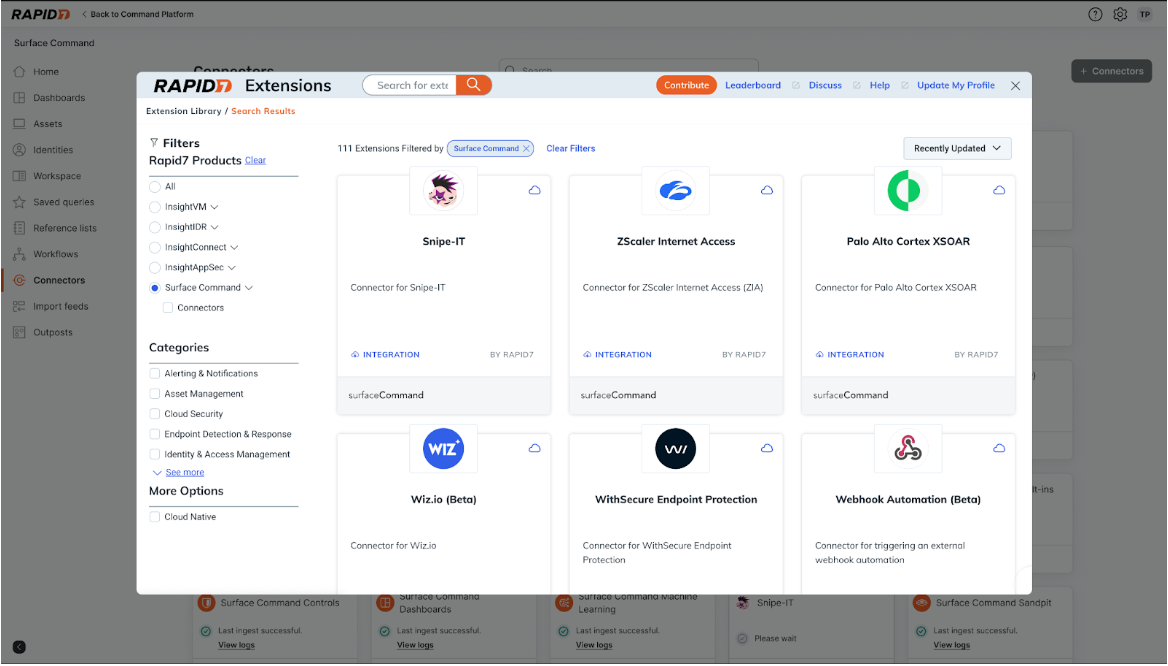
Surface Command customers can now install connectors at their own convenience via the Rapid7 Extensions Library, making it faster and easier to gain visibility into cyber asset insights across your security and IT management tools. Customers can choose from over 100 out-of-the-box connectors to ingest and enrich asset data within Surface Command, consolidating insights from across your entire security ecosystem into one place.

What’s New in Rapid7 Products & Services: Q4 2024 in Review
Surface Command connectors in Rapid7 Extensions Library

Pinpoint critical signals and act confidently against threats with cloud-ready detection and response

A Growing Ecosystem of Cloud Event Sources in InsightIDR and MDR

At Rapid7, we understand that organizations are tasked with collecting and correlating vast amounts of data across their unique ecosystems. To tackle this, teams need faster, more dynamic mechanisms to ingest cloud data directly into their SIEM tool. We addressed this earlier this year with cloud event sources, providing a native cloud collection framework that can receive log data from cloud platforms directly – without requiring installation of collector software in their cloud and on-premise environments.

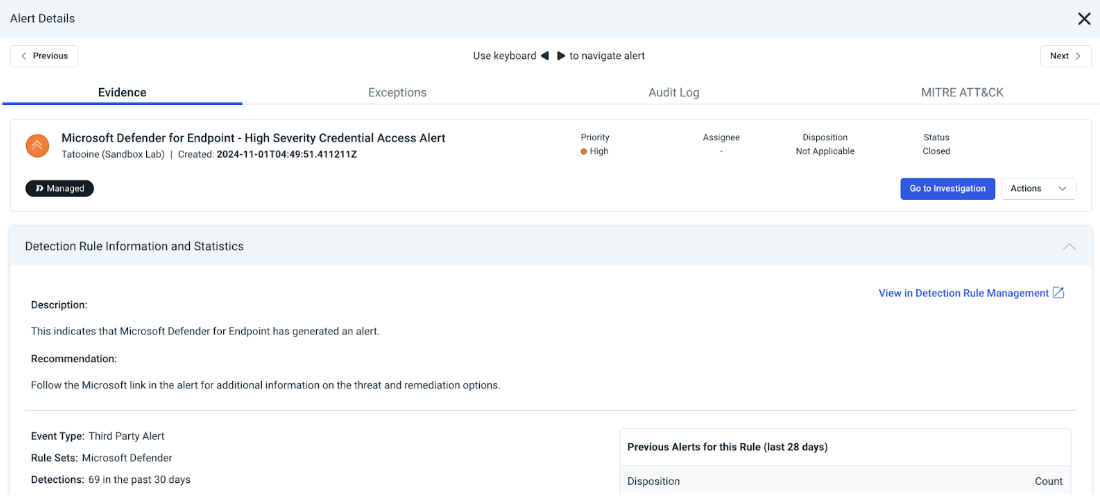
This quarter, we further expanded our list of cloud event sources by adding support for Microsoft products, including: Defender for Endpoint, Defender for Cloud, Defender for Identity, Defender for Cloud Apps, Defender O365, Defender for Vulnerability Management, and Entra ID.

MXDR: Expanded Support for Microsoft & AWS

In our Q3 “What’s New” blog, we announced the launch of Rapid7 MDR for the Extended Ecosystem (MXDR), which expands our MDR service to triage, investigate, and respond to alerts from third-party tools within customer organizations. Now, we’re excited to announce that we have updated our MXDR to support an expanded subset of detections across AWS GuardDuty and Microsoft security tools, bringing more protection to customer environments across a broader group of security tools.

Furthering our commitment to keep organizations safe and ahead of adversaries in today’s complex threat landscape, this update includes:

  • Deepened existing support for Microsoft security tools like Defender for Endpoint, Defender for Cloud, and AWS GuardDuty
  • Expanded support (via aforementioned cloud event sources) to critical alerts across Defender for Identity, Microsoft O365, Defender for Vulnerability Management, and Microsoft Entra
What’s New in Rapid7 Products & Services: Q4 2024 in Review
Example Microsoft Defender for Endpoint alert

Expanded Coverage for Next-Gen Antivirus: MacOS and Linux

We’ve extended operating system coverage for Next-Gen AV (NGAV) support beyond Windows OS to now include protection capabilities for MacOS and Linux. Now, customers utilizing NGAV don’t have to utilize multiple point systems across the operating systems within their detection surface to stop breaches as early as possible in the kill chain.

The latest research and intelligence from Rapid7 Labs

2024 Threat Landscape Statistics

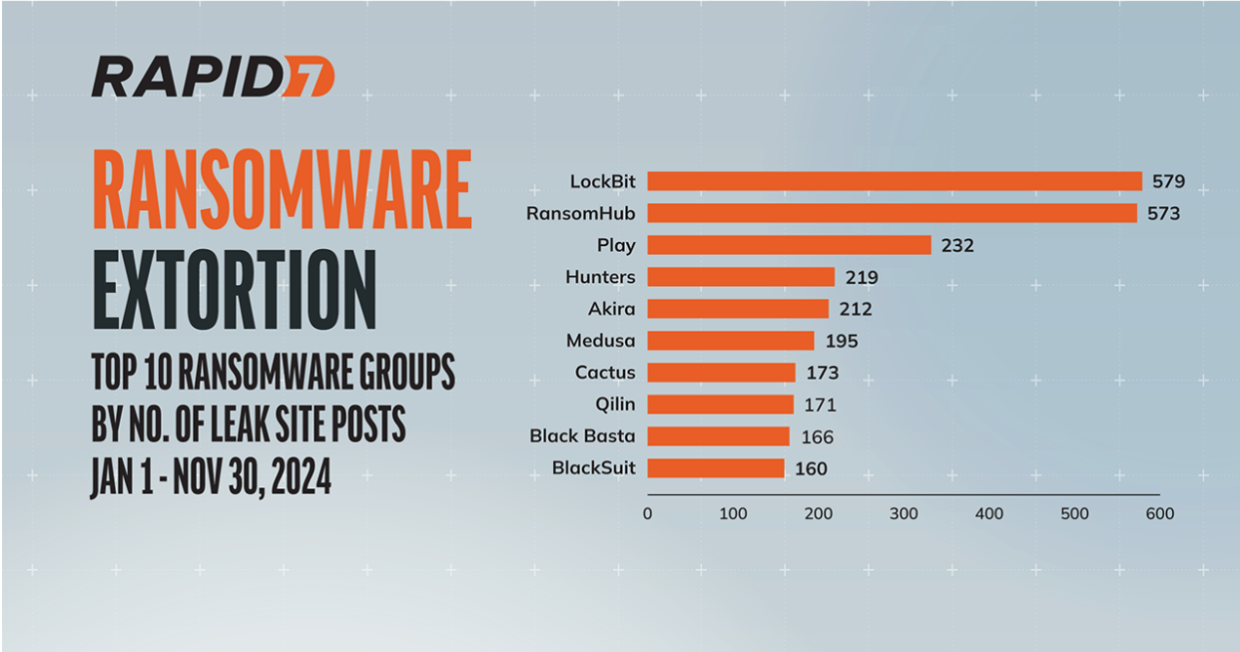
This year, Rapid7’s global Managed Services team and Rapid7 Labs researchers responded to hundreds of major incidents, significant vulnerabilities, and ransomware threats—delivering emergent threat guidance, research reports, and other vulnerability and threat content for customers. See the roundup of key statistics and trends from our Rapid7 Labs team in our recent blog post, here.

What’s New in Rapid7 Products & Services: Q4 2024 in Review
Example of findings presented in the 2024 Threat Landscape Statistics: Ransomware Activity, Vulnerability Exploits, and Attack Trends from Rapid7 Labs

Emergent Threat Response: Real-time Guidance for Critical Threats

Rapid7’s Emergent Threat Response (ETR) program from Rapid7 Labs delivers fast, expert analysis and first-rate security content for the highest-priority security threats to help both Rapid7 customers and the greater security community understand their exposure and act quickly to defend their networks against rising threats.

In Q4, Rapid7’s ETR team provided expert analysis, InsightIDR and InsightVM content, and mitigation guidance for multiple critical, actively exploited vulnerabilities and widespread attacks, including:

Follow along here to receive the latest emergent threat guidance from our team.

Stay tuned for more!

As always, we’re continuing to work on exciting product enhancements and releases throughout the year. Keep an eye on our blog and release notes as we continue to highlight the latest in product and service investments at Rapid7.

Спайдър-Мен срещу чалгата, или за необходимостта от популярна масова култура

Post Syndicated from original https://www.toest.bg/spiderman-sreshtu-chalghata-ili-za-neobhodimostta-ot-populyarna-masova-kultura/

Спайдър-Мен срещу чалгата, или за необходимостта от популярна масова култура

Навремето, докато още следвах магистратура в Софийския университет, изтръпнах, когато в една от лекциите покойният професор Петър-Емил Митев цитира мисъл на Мао Дзъдун, според която празните съзнания са най-хубави, тъй като са бели листове и върху тях можеш да напишеш всичко. Много може да се каже за откровения цинизъм на диктатора, известен с това, че по време на Културната революция използва необразовани младежи, за да тероризира хората на изкуството и науката. Трябва обаче да признаем, че той доста вярно е осъзнал възможността с помощта на пропагандата да програмира още бедни на житейски опит хора в една или друга посока. 

В демократичните общества подобна работа в смекчен вариант върши масовата култура – тази, която се потребява от хората и особено от младите в ежедневието им. Точно тук ми се струва, че като общество България има проблем, тъй като се опираме на изключително богатата си традиция от времената преди, около и след Освобождението, но изпускаме съвремието.

Можем ли да сме фенове на собствената си култура?

Факт е, че възходът на българската култура, започнал по време на Възраждането и продължил до налагането на комунистическата диктатура на 9 септември 1944 г., буди възхищение. Още от времената на Пенчо Славейков е популярно да се търсят кусури на Иван Вазов, но истината е, че делото му е внушително. Той сам-самичък създава корпус от текстове, достатъчно голям, за да положи основите на бъдещото развитие на литературата у нас, а една сериозна част от тях са наистина на много високо ниво. Повечето съвременни читатели познават Вазов най-вече с „Под игото“ и с някои от стихотворенията му, но той има голям набор от текстове – от хумористични до приключенски. 

В по-късен етап от развитието на книжнината ни силно впечатление прави творчеството на Йордан Йовков и Елин Пелин, като в „Гераците“ според мен виждаме най-точното диагностициране на архетиповете в българската народопсихология, въплътени в образите на тримата братя. Още преди тях нещо подобно обаче прави и Алеко Константинов – не само с широко цитирания „Бай Ганьо“, но и с незаслужено подценявания разказ „Пази боже сляпо да прогледа“. Каквото и да кажем за поезията ни пък, ще е малко. Имената на Ботев, Яворов, Дебелянов, Смирненски и Вапцаров заслужено са записани със златни букви в историята ни и е напълно нормално да се преподават в училище и в университета, макар да не съм убеден, че един тийнейджър може напълно да осмисли всичките им текстове, особено пречупени през обобщенията в христоматиите.

В същото време трябва да сме честни: всички тези автори са далеч от съзнанието и вълненията на повечето юноши. Една от причините за това е начинът, по който ги преподаваме – като свещени писания, пред които можем само да се прекланяме, но като че ли не можем да почувстваме като – ще ме извините за съвременния термин – фенове. Друга причина обаче е самото естество на юношеството, когато се формираме като личности, застанали на границата между детството и зрелостта. Ако трябва да бъдем откровени, едва ли и американските тийнейджъри прекарват петък вечер зачетени в томовете на Стайнбек и Хемингуей, при цялото ми уважение към онези от тях, които го правят. Съмнявам се и голяма част от руските юноши да издържат на класиците Достоевски и Толстой. 

Какво искат младите хора и къде го намират?

Младите копнеят за истории, близки до тях, до емоциите им, до мястото, на което са самите те в живота – между невинността и съзряването. Докато голямата и сериозна литература сякаш предполага известен житейски опит, за да я оцениш истински и по достойнство.

Затова и тийнейджърите, за голямо раздразнение на родители и още повече на учители, често посягат към остросюжетните жанрове, като фентъзи и ужаси, понякога към комикси, често филмирани от Холивуд или пък нарисувани от японската анимация. И колкото и невероятно да звучи, преживяват много с тях, учат се на емпатия от героите им, попиват някои общочовешки ценности, получават простички, но важни дефиниции за доброто и злото и дори да не направят следващата крачка към класиката, водят някакъв духовен живот. За целта обаче трябва да имат тази възможност.

Ясно е, че американчетата в това отношение са най-облагодетелствани. Философията на САЩ, че всеки човек, ако е добър, може да успее, и кредото, че дори и да се провалиш, важното е да си опитал, вместо да живуркаш на сигурно, са направили така, че много хора са си създали кариера с умението да разказват истории, които да стигат до младите. Може да започнем с цялата плеяда автори на комикси от началото на миналия век – Джери Сийгъл и Джо Шустър, Боб Кейн и Бил Фингър, Стан Лий и Стив Дитко, създали супергероите Батман, Супермен и Спайдър-Мен, да минем през писатели като Франк Хърбърт, Стивън Кинг и Джордж Р.Р. Мартин и да стигнем до холивудските магьосници Лукас и Спилбърг. Ще видим, че тези хора са отговорни за голяма част от епосите на нашето време, истории, които в някаква степен играят ролята, изпълнявана в древността от Омировите поеми, а през средните векове – от рицарските романи, с тази разлика, че не са запазени за висшата класа, а са достъпни за всеки. И макар много от техните произведения да са отричани от сериозната критика като комерсиални, те формират определени ценности и базова етика.

Йода, докато шава с големите си уши, учи, че макар и по-лесен, пътят на гнева и омразата води до гибел; Батман, при все страховития си външен вид, отказва да убива дори най-големите престъпници; а Спайдър-Мен, освен че се катери по небостъргачи в прилепнал костюм, казва, че с голямата сила идва и голямата отговорност. Все още помня как гледах сцените във филмите на Сам Рейми за Човека паяк, в които обикновени хора се опитваха да му се притекат на помощ. Голяма част от публиката в киносалона у нас започна да се подхилква и още тогава на инстинктивно ниво разбрах, че има някакъв проблем, макар още да не осъзнавах точно какъв. Проблемът е, че при нас самата концепция за солидарност – да се подложиш на опасност заради някой друг – буди присмех.

Британците, независимо че разчитат на вековна литературна традиция с автори като Шекспир и Дикенс, никак не отстъпват и плениха света с „Властелинът на пръстените“ от Джон Р.Р. Толкин в средата на ХХ век, а после и с „Хари Потър“ в началото на XXI, като има статистики, че поредицата на Дж. К. Роулинг не само запалва цяло едно ново поколение за четенето, но и увеличава умението му да съчувства. Японците, които винаги са умеели да съчетават високото и популярното изкуство, накараха целия свят да гледа аниме, а истории като „Железният алхимик“ на Хирому Аракава отправиха посланието, че трябва повече да се стремиш да даваш, отколкото да вземаш. 

Къде обаче сме ние? 

Българската култура действително е в подем в последните години, като наградата „Букър“ за „Времеубежище“ от Георги Господинов е доказателство за развитието на литературата ни, маркирано и от успехи като получилия филмова адаптация „Възвишение“ от Милен Русков и романите на Захари Карабашлиев. Това обаче сякаш са произведения все за зрели хора, да не кажа за хуманитаристи, а в произведенията за подрастващи никакви ни няма. Белите листове на младите умове останаха празни, а върху тях чалгата написа онази пуста думичка от три букви, която редовно виждаме надраскана със спрей къде ли не.

Не искам да бъда разбиран погрешно. Всеки има право да слуша каквото си иска. Но когато изборът е беден, чалгата дава храна, която е изключително оскъдна откъм витамини за душата. Тук мерило за успеха са парите, мечтата е момчето да стане богаташ с беемве, а момичето – плеймейтка и бъдеща негова половинка със силиконов бюст. Учудва ли ни тогава това, че голяма част от младите хора са хиперпрагматични, лишени от съчувствие и от мечти (извън успеха на битово ниво).

Не по-малък проблем има и с част от масовите заглавия, които все пак бележат успех. Книгата „Стопанката на Господ“ от Розмари де Мео е сръчно написана и в нея има симпатични хрумки, но наред с това проповядва мислене за България като обсадена крепост – че светът наоколо е враждебен и ние трябва да сме настръхнали срещу него. Лично аз се отказах от тази книга, когато прочетох в нея, че дори с италианците не можем да осъществим контакт. В „Бабо, разкажи ми спомен“ между уюта и вкусните рецепти има вмъкната хомофобска нишка. Знайни и незнайни автори тракат произведения на струната на крайния национализъм с твърдения от типа на това, че крал Артур е българин или че гърците са ни откраднали историята. Нашето е добро, чуждото е лошо – светоглед, завещан от литературата на късния социализъм, която от своя страна е наследница на нискокачествените партизански романи от ранния. След подобни четива няма да е учудващо, ако в един момент се окаже, че младите, които изобщо си направят труда да гласуват, ще пускат бюлетини в подкрепа на популистки партии. 

Въпросът е дали има изход от това

Опитът на България показва, че би трябвало. Най-ярък пример е успехът на „Гунди“, показал, че все още можем да разказваме истории, които да развълнуват голям брой хора у нас. Трябва да имаме предвид, че сме изправени пред много трудна ситуация, в която умението ни да се съсредоточаваме е ерозирано от платформи като TikTok и Instagram, целенасочено направени така, че вниманието да не се захваща за нищо, а постоянно да се търсят нови и нови неща. В резултат вече дори гледането на пълнометражен филм се превръща в трудна задача, да не говорим за прочитането на цяла книга.

Не съм съгласен и не приветствам тезата, че западната култура ще надделее над националната, за да формира ценностите на по-голямата част от младите хора. За мен не е добра стратегия да се разчита на това – по няколко причини. Първо, тя не е правена за нас и не е съвсем сигурно, че може да достигне до потребителите тук със същия успех, с който го прави сред основната си аудитория – хората от държавите, в които е създадена. Преведено на прост език, ние, българите, изпускаме много неща от „Хари Потър“, които англичаните улавят. Преди време в разговор с актьора Станислав Яневски (изиграл една от епизодичните роли във филмите от поредицата) научих, че „Хогуортс“, като изключим магиите, е почти реалистично училище, а разделянето на домове и състезанията си ги има и в британските пансиони. 

Второ, западната култура не е лишена от недостатъци, особено във варианта си от последните десет години. Най-малкото, окрупняването на развлекателните компании и в киното, и в литературата направи културата свръхкорпоративна и доведе до пресушаване на новите идеи – не е случайно, че на екран излизат само продължения и епизоди от поредици, а на хартия най-вървежни остават основно все едни и същи автори, изгрели в края на миналия или началото на този век. 

На трето място, ако се върнем към България, през десетилетията сме доказвали, че можем да създаваме качествени автори със силни произведения. Така бихме били ценни и за новото глобално село, в което, макар и мъчително, се превръща светът – не само като пасивна страна, която потребява, но и като активна, умееща да създава. Това трудно ще стане с патриотична литература колко сме велики и как другите са лоши, а няма и нужда. 

По-паметливите фенове на фантастиката си спомнят и приключенските романи на Петър Бобев, като „Каменното яйце“ (1989), разказващ за избягали в Африка тиранозаври години преди „Джурасик парк“, макар твърденията, че Крайтън е вдъхновен от нашия автор, да са малко пресилени (за любопитните – подобен сюжет се появява години по-рано, през 1984 г., в романа Carnosaur на Хари Адам Найт).

За съжаление, вече са забравени книжки като „Педра Пинтада“ на Ангел Сарафов, но за сметка на това мнозина все още са запалени по книгите игри, превърнали се във феномен на родния пазар през 90-те години. Макар и творящи под западни псевдоними, автори като Любомир Николов – Нарви, Георги Миндизов и Богдан Русев създаваха завладяващи приключения, които не само пленяваха въображението на читателите, но и съумяваха да им създадат представи за добро и зло.

Особено изкусен в това отношение беше отишлият си по-рано през тази година Нарви, винаги възнаграждаващ в интерактивните си сюжети моралния избор. Думите ми не стигат да изразя колко ценен беше той лично за мен в един момент, когато за много младежи от моето поколение в идоли се превръщаха героите от криминалната хроника с лъскавите си германски лимузини, тежки мобифони и леки жени, подпяващи попфолк около тях.

В наши дни има сполучливи опити в популярната литература и затова се зарадвах да науча, че романът „Мамник“ от Васил Попов ще бъде адаптиран като филмов сериал. Потенциал показа и поредицата „Софийски магьосници“ на Мартин Колев, започнаха наново да излизат книги игри. Проблемът обаче е, че поне засега тези произведения остават в сравнително по-затворен кръг, най-често на градската интелигенция, която малко или много вече води активен културен живот. Хубаво е, че тя не е оставена да разчита само на преводни творби, но за съжаление, не е достатъчно. Трябва да се измисли начин да се стигне до широк кръг зрители и читатели, особено млади хора, така че те да получат някакви ориентири за добро и зло и в същото време да не става дума за крайния национализъм, делящ всичко на наше и чуждо. 

Въпросът как да стане това, е, както се казва, за един милион долара, а часовникът отдавна тиктака. Може би обаче е ясно как няма да стане. Ако заклеймяваме младите хора и нещата, които обичат – аниме, комикси и видеоигри, – със сигурност няма да успеем да направим нищо, освен да ги отчуждим тотално от опитите ни да осъществим контакт с тях. Преди години писателят Рик Риърдън, по онова време учител по литература, беше споделил, че се е чудил защо учениците му четат само „Хари Потър“, и когато разбрал, че имат потребност от книги с подобен емоционален заряд, създал поредицата „Пърси Джаксън“, на свой ред превърнала се в хит. Може би хората, занимаващи се с култура, имаме нужда от подобен подход – първо да чуем младите. И чак след това да опитаме да ги заговорим.

Part 1: A Survey of Analytics Engineering Work at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/part-1-a-survey-of-analytics-engineering-work-at-netflix-d761cfd551ee

This article is the first in a multi-part series sharing a breadth of Analytics Engineering work at Netflix, recently presented as part of our annual internal Analytics Engineering conference. We kick off with a few topics focused on how we’re empowering Netflix to efficiently produce and effectively deliver high quality, actionable analytic insights across the company. Subsequent posts will detail examples of exciting analytic engineering domain applications and aspects of the technical craft.

At Netflix, we seek to entertain the world by ensuring our members find the shows and movies that will thrill them. Analytics at Netflix powers everything from understanding what content will excite and bring members back for more to how we should produce and distribute a content slate that maximizes member joy. Analytics Engineers deliver these insights by establishing deep business and product partnerships; translating business challenges into solutions that unblock critical decisions; and designing, building, and maintaining end-to-end analytical systems.

Each year, we bring the Analytics Engineering community together for an Analytics Summit — a 3-day internal conference to share analytical deliverables across Netflix, discuss analytic practice, and build relationships within the community. We covered a broad array of exciting topics and wanted to spotlight a few to give you a taste of what we’re working on across Analytics Engineering at Netflix!

DataJunction: Unifying Experimentation and Analytics

Yian Shang, Anh Le

At Netflix, like in many organizations, creating and using metrics is often more complex than it should be. Metric definitions are often scattered across various databases, documentation sites, and code repositories, making it difficult for analysts and data scientists to find reliable information quickly. This fragmentation leads to inconsistencies and wastes valuable time as teams end up reinventing metrics or seeking clarification on definitions that should be standardized and readily accessible.

Enter DataJunction (DJ). DJ acts as a central store where metric definitions can live and evolve. Once a metric owner has registered a metric into DJ, metric consumers throughout the organization can apply that same metric definition to a set of filtered records and aggregate to any dimensional grain.

As an example, imagine an analyst wanting to create a “Total Streaming Hours” metric. To add this metric to DJ, they need to provide two pieces of information:

  • The fact table that the metric comes from:

SELECT
account_id, country_iso_code, streaming_hours
FROM streaming_fact_table

  • The metric expression:

`SUM(streaming_hours)`

Then metric consumers throughout the organization can call DJ to request either the SQL or the resulting data. For example,

  • total_streaming_hours of each account:

dj.sql(metrics=[“total_streaming_hours”], dimensions=[“account_id”]))

  • total_streaming_hours of each country:

dj.sql(metrics=[“total_streaming_hours”], dimensions=[“country_iso_code”]))

  • total_streaming_hours of each account in the US:

dj.sql(metrics=[“total_streaming_hours”], dimensions=[“country_iso_code”], filters=[“country_iso_code = ‘US’”]))

The key here is that DJ can perform the dimensional join on users’ behalf. If country_iso_code doesn’t already exist in the fact table, the metric owner only needs to tell DJ that account_id is the foreign key to an `users_dimension_table` (we call this process “dimension linking”). DJ then can perform the joins to bring in any requested dimensions from `users_dimension_table`.

The Netflix Experimentation Platform heavily leverages this feature today by treating cell assignment as just another dimension that it asks DJ to bring in. For example, to compare the average streaming hours in cell A vs cell B, the Experimentation Platform relies on DJ to bring in “cell_assignment” as a user’s dimension (no different from country_iso_code). A metric can therefore be defined once in DJ and be made available across analytics dashboards and experimentation analysis.

DJ has a strong pedigree–there are several prior semantic layers in the industry (e.g. Minerva at Airbnb; dbt Transform, Looker, and AtScale as paid solutions). DJ stands out as an open source solution that is actively developed and stress-tested at Netflix. We’d love to see DJ easing your metric creation and consumption pain points!

LORE: How we’re democratizing analytics at Netflix

Apurva Kansara

At Netflix, we rely on data and analytics to inform critical business decisions. Over time, this has resulted in large numbers of dashboard products. While such analytics products are tremendously useful, we noticed a few trends:

  1. A large portion of such products have less than 5 MAU (monthly active users)
  2. We spend a tremendous amount of time building and maintaining business metrics and dimensions
  3. We see inconsistencies in how a particular metric is calculated, presented, and maintained across the Data & Insights organization.
  4. It is challenging to scale such bespoke solutions to ever-changing and increasingly complex business needs.

Analytics Enablement is a collection of initiatives across Data & Insights all focused on empowering Netflix analytic practitioners to efficiently produce and effectively deliver high-quality, actionable insights.

Specifically, these initiatives are focused on enabling analytics rather than on the activities that produce analytics (e.g., dashboarding, analysis, research, etc.).

As part of broad analytics enablement across all business domains, we invested in a chatbot to provide real insights to our end users using the power of LLM. One reason LLMs are well suited for such problems is that they tie the versatility of natural language with the power of data query to enable our business users to query data that would otherwise require sophisticated knowledge of underlying data models.

Besides providing the end user with an instant answer in a preferred data visualization, LORE instantly learns from the user’s feedback. This allows us to teach LLM a context-rich understanding of internal business metrics that were previously locked in custom code for each of the dashboard products.

Some of the challenges we run into:

  • Gaining user trust: To gain our end users’ trust, we focused on our model’s explainability. For example, LORE provides human-readable reasoning on how it arrived at the answer that users can cross-verify. LORE also provides a confidence score to our end users based on its grounding in the domain space.
  • Training: We created easy-to-provide feedback using 👍 and 👎 with a fully integrated fine-tuning loop to allow end-users to teach new domains and questions around it effectively. This allowed us to bootstrap LORE across several domains within Netflix.

Democratizing analytics can unlock the tremendous potential of data for everyone within the company. With Analytics enablement and LORE, we’ve enabled our business users to truly have a conversation with the data.

Leveraging Foundational Platform Data to enable Cloud Efficiency Analytics

J Han, Pallavi Phadnis

At Netflix, we use Amazon Web Services (AWS) for our cloud infrastructure needs, such as compute, storage, and networking to build and run the streaming platform that we love. Our ecosystem enables engineering teams to run applications and services at scale, utilizing a mix of open-source and proprietary solutions. In order to understand how efficiently we operate in this diverse technological landscape, the Data & Insights organization partners closely with our engineering teams to share key efficiency metrics, empowering internal stakeholders to make informed business decisions.

This is where our team, Platform DSE (Data Science Engineering), comes in to enable our engineering partners to understand what resources they’re using, how effectively they utilize those resources, and the cost associated with their resource usage. By creating curated datasets and democratizing access via a custom insights app and various integration points, downstream users can gain granular insights essential for making data-driven, cost-effective decisions for the business.

To address the numerous analytic needs in a scalable way, we’ve developed a two-component solution:

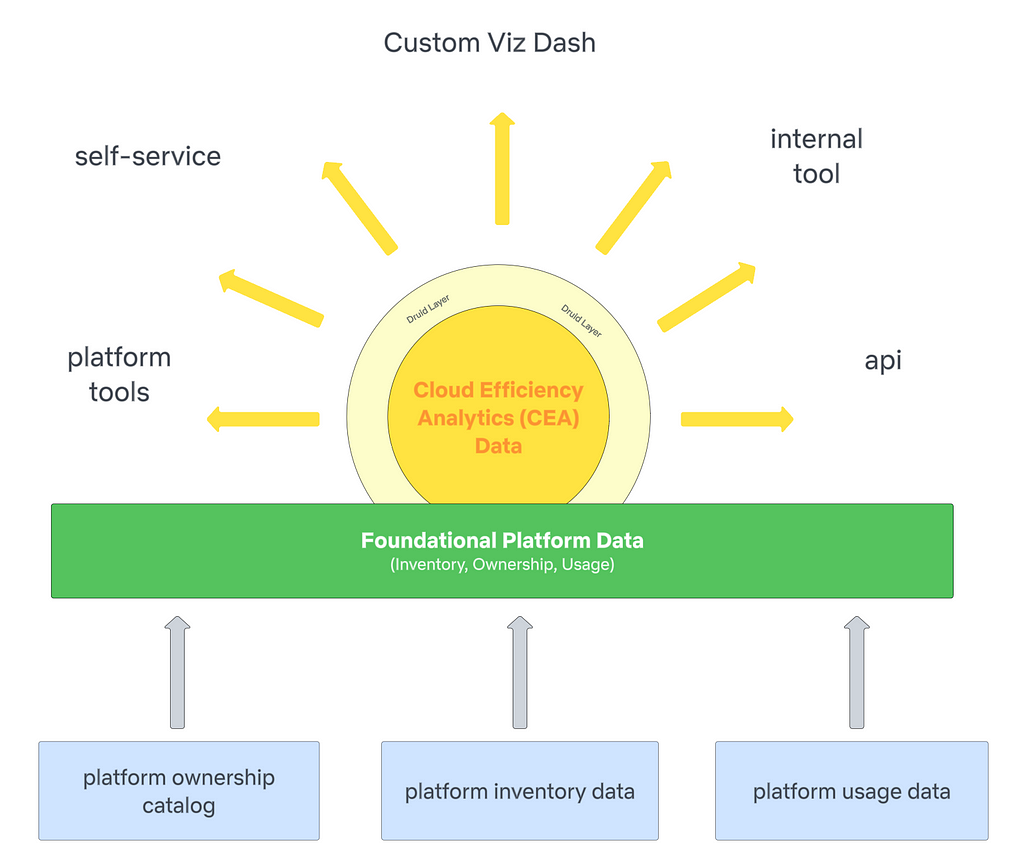
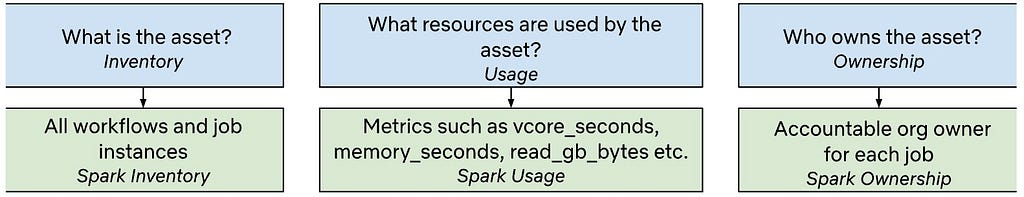
  1. Foundational Platform Data (FPD): This component provides a centralized data layer for all platform data, featuring a consistent data model and standardized data processing methodology. We work with different platform data providers to get inventory, ownership, and usage data for the respective platforms they own.
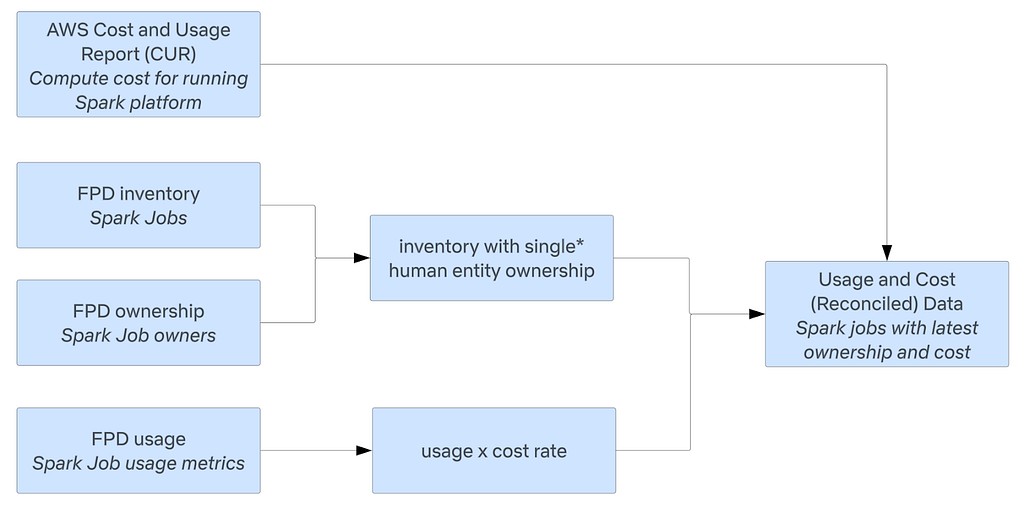
  2. Cloud Efficiency Analytics (CEA): Built on top of FPD, this component offers an analytics data layer that provides time series efficiency metrics across various business use cases. Once the foundational data is ready, CEA consumes inventory, ownership, and usage data and applies the appropriate business logic to produce cost and ownership attribution at various granularities.

As the source of truth for efficiency metrics, our team’s tenants are to provide accurate, reliable, and accessible data, comprehensive documentation to navigate the complexity of the efficiency space, and well-defined Service Level Agreements (SLAs) to set expectations with downstream consumers during delays, outages, or changes.

Looking ahead, we aim to continue onboarding platforms, striving for nearly complete cost insight coverage. We’re also exploring new use cases, such as tailored reports for platforms, predictive analytics for optimizing usage and detecting anomalies in cost, and a root cause analysis tool using LLMs.

Ultimately, our goal is to enable our engineering organization to make efficiency-conscious decisions when building and maintaining the myriad of services that allows us to enjoy Netflix as a streaming service. For more detail on our modeling approach and principles, check out this post!

Analytics Engineering is a key contributor to building our deep data culture at Netflix, and we are proud to have a large group of stunning colleagues that are not only applying but advancing our analytical capabilities at Netflix. The 2024 Analytics Summit continued to be a wonderful way to give visibility to one another on work across business verticals, celebrate our collective impact, and highlight what’s to come in analytics practice at Netflix.

To learn more, follow the Netflix Research Site, and if you are also interested in entertaining the world, have a look at our open roles!


Part 1: A Survey of Analytics Engineering Work at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Enhance Your Email Campaigns using Amazon SES SendBulkEmail APIs Inline Templates

Post Syndicated from Satya S Tripathy original https://aws.amazon.com/blogs/messaging-and-targeting/enhance-your-email-campaigns-using-amazon-ses-sendbulkemail-apis-inline-templates/

Amazon Simple Email Service (SES) is a cloud-based email sending service provided by Amazon Web Services (AWS), handling both inbound and outbound email traffic for your applications. It allows users to send and receive email using SES’s reliable and cost-effective infrastructure without having to provision email servers yourself. Customers use Amazon SES to send emails like one time passwords (OTPs), transactional emails such as order confirmation, and promotional/marketing emails.

For this post, you should be familiar with the following:

Amazon SES continues to evolve, offering new features that help you simplify and optimize your email campaigns. We’re excited to announce the addition of inline template support for both the SendEmail and SendBulkEmail APIs. This new capability allows you to include template content directly in your API requests, reducing complexity and eliminating the need to manage separate template resources in your SES account.

What are inline templates?

Inline templates allow you to provide the subject, HTML body, and text body of an email directly in the API request, along with dynamic placeholders for personalized content. Instead of creating and storing a separate email template in SES, you can define the template as part of your API call. This feature is especially useful for organizations that need flexibility in managing numerous templates or want to make quick adjustments to email content.

How inline templates simplify your workflow

Previously, Amazon SES required you to create and store email templates in your SES account, which you would then reference by name or Amazon Resource Name (ARN) when sending an email. This process adds some management overhead, particularly for organizations that frequently create new templates or exceed the limit of templates per AWS Region. With inline templates, you can reduce complexity by defining your email content directly in the API payload, avoiding the need to create and manage stored templates. This approach can improve flexibility, allowing you to quickly make changes to your email content without updating stored templates. Additionally, it can simplify your integration by providing template content directly within your application logic, making the process more seamless and efficient. When using the and SendBulkEmail API, you can include personalized content for up to 50 destinations in a single call, making large-scale communication more efficient.

How to use inline templates

To use inline templates, you simply provide the email content (subject, text, HTML) and the replacement data directly in the SendBulkEmail API request payload within TemplateContent parameter.

Inline-template API

Here’s an example for using the SendBulkEmail API with inline templates:

file://mybulkemail-inline-template-conten.json:

{
    "FromEmailAddress": "Mary Major <[email protected]>",
    "DefaultContent": {
        "Template": {
            "TemplateContent": {
                "Subject": "Greetings, {{name}}!",
                "Text": "Dear {{name}},\r\nYour favorite animal is {{favoriteanimal}}.",
                "Html": "<h1>Hello {{name}},</h1><p>Your favorite animal is {{favoriteanimal}}.</p>"
            },
            "TemplateData": "{ \"name\":\"friend\", \"favoriteanimal\":\"unknown\" }"
        }
    },
    "BulkEmailEntries": [
        {
            "Destination": {
                "ToAddresses": [
                    "[email protected]"
                ]
            },
            "ReplacementEmailContent": {
                "ReplacementTemplate": {
                    "ReplacementTemplateData": "{ \"name\":\"Anaya\", \"favoriteanimal\":\"angelfish\" }"
                }
            }
        },
        {
            "Destination": {
                "ToAddresses": [
                    "[email protected]"
                ]
            },
            "ReplacementEmailContent": {
                "ReplacementTemplate": {
                    "ReplacementTemplateData": "{ \"name\":\"Liu\", \"favoriteanimal\":\"lion\" }"
                }
            }
        }
    ],
    "ConfigurationSetName": "ConfigSet"
}

SES SendBulkEmail API call:

aws sesv2 send-bulk-email -cli-input-json file://mybulkemail-inline-template-conten.json

Output:

{
    "BulkEmailEntryResults": [
        {
            "Status": "SUCCESS",
            "MessageId": "010001xxxxxx-xxxxxxxx-xxxx-xxxx-000000"
        },
        {
            "Status": "SUCCESS",
            "MessageId": "020002xxxxxx-xxxxxxxx-xxxx-xxxx-000000"
        }
    ]
}

Backward compatibility

If you’re currently using stored templates, don’t worry – Amazon SES still supports the use of stored templates, and you can continue to use them without any changes. Inline templates are simply an additional option for customers who need more flexibility or wish to avoid managing stored templates altogether. Since inline templates only support the use of simple substitution, stored templates remain the solution for advanced personalization options such as conditional logic or complex formatting. More details in our doc link: How to use Bulk email template.

Get started today

The inline template feature is now available in all AWS Regions where Amazon SES is offered. To start using inline templates, refer to the Amazon SES Developer Guide and what’s new announcement. There are no additional charges applicable for using inline template feature.

Conclusion

The inline templating feature in SendBulkEmail allows you to avoid worrying about template management by updating / creating new email templates whenever a minor modification or alteration is required in the existing templates, as well as cleaning up unused templates on a regular basis. Therefore, if your business has a high number of email template requirements, there are no predefined rules or patterns for creating email templates, and you need to generate many templates simultaneously within Amazon SES, you must use inline templating feature of SendBulkEmail API . If you do not want to use the Inline templating capability, you can continue to use the templated SendBulkEmail API from Amazon SES.

Cloud Efficiency at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/cloud-efficiency-at-netflix-f2a142955f83

By J Han, Pallavi Phadnis

Context

At Netflix, we use Amazon Web Services (AWS) for our cloud infrastructure needs, such as compute, storage, and networking to build and run the streaming platform that we love. Our ecosystem enables engineering teams to run applications and services at scale, utilizing a mix of open-source and proprietary solutions. In turn, our self-serve platforms allow teams to create and deploy, sometimes custom, workloads more efficiently. This diverse technological landscape generates extensive and rich data from various infrastructure entities, from which, data engineers and analysts collaborate to provide actionable insights to the engineering organization in a continuous feedback loop that ultimately enhances the business.

One crucial way in which we do this is through the democratization of highly curated data sources that sunshine usage and cost patterns across Netflix’s services and teams. The Data & Insights organization partners closely with our engineering teams to share key efficiency metrics, empowering internal stakeholders to make informed business decisions.

Data is Key

This is where our team, Platform DSE (Data Science Engineering), comes in to enable our engineering partners to understand what resources they’re using, how effectively and efficiently they use those resources, and the cost associated with their resource usage. We want our downstream consumers to make cost conscious decisions using our datasets.

To address these numerous analytic needs in a scalable way, we’ve developed a two-component solution:

  1. Foundational Platform Data (FPD): This component provides a centralized data layer for all platform data, featuring a consistent data model and standardized data processing methodology.
  2. Cloud Efficiency Analytics (CEA): Built on top of FPD, this component offers an analytics data layer that provides time series efficiency metrics across various business use cases.

Foundational Platform Data (FPD)

We work with different platform data providers to get inventory, ownership, and usage data for the respective platforms they own. Below is an example of how this framework applies to the Spark platform. FPD establishes data contracts with producers to ensure data quality and reliability; these contracts allow the team to leverage a common data model for ownership. The standardized data model and processing promotes scalability and consistency.

Cloud Efficiency Analytics (CEA Data)

Once the foundational data is ready, CEA consumes inventory, ownership, and usage data and applies the appropriate business logic to produce cost and ownership attribution at various granularities. The data model approach in CEA is to compartmentalize and be transparent; we want downstream consumers to understand why they’re seeing resources show up under their name/org and how those costs are calculated. Another benefit to this approach is the ability to pivot quickly as new or changes in business logic is/are introduced.

* For cost accounting purposes, we resolve assets to a single owner, or distribute costs when assets are multi-tenant. However, we do also provide usage and cost at different aggregations for different consumers.

Data Principles

As the source of truth for efficiency metrics, our team’s tenants are to provide accurate, reliable, and accessible data, comprehensive documentation to navigate the complexity of the efficiency space, and well-defined Service Level Agreements (SLAs) to set expectations with downstream consumers during delays, outages or changes.

While ownership and cost may seem straightforward, the complexity of the datasets is considerably high due to the breadth and scope of the business infrastructure and platform specific features. Services can have multiple owners, cost heuristics are unique to each platform, and the scale of infra data is large. As we work on expanding infrastructure coverage to all verticals of the business, we face a unique set of challenges:

A Few Sizes to Fit the Majority

Despite data contracts and a standardized data model on transforming upstream platform data into FPD and CEA, there is usually some degree of customization that is unique to that particular platform. As the centralized source of truth, we feel the constant tension of where to place the processing burden. Decision-making involves ongoing transparent conversations with both our data producers and consumers, frequent prioritization checks, and alignment with business needs as informed captains in this space.

Data Guarantees

For data correctness and trust, it’s crucial that we have audits and visibility into health metrics at each layer in the pipeline in order to investigate issues and root cause anomalies quickly. Maintaining data completeness while ensuring correctness becomes challenging due to upstream latency and required transformations to have the data ready for consumption. We continuously iterate our audits and incorporate feedback to refine and meet our SLAs.

Abstraction Layers

We value people over process, and it is not uncommon for engineering teams to build custom SaaS solutions for other parts of the organization. Although this fosters innovation and improves development velocity, it can create a bit of a conundrum when it comes to understanding and interpreting usage patterns and attributing cost in a way that makes sense to the business and end consumer. With clear inventory, ownership, and usage data from FPD, and precise attribution in the analytical layer, we aim to provide metrics to downstream users regardless of whether they utilize and build on top of internal platforms or on AWS resources directly.

Future Forward

Looking ahead, we aim to continue onboarding platforms to FPD and CEA, striving for nearly complete cost insight coverage in the upcoming year. Longer term, we plan to extend FPD to other areas of the business such as security and availability. We aim to move towards proactive approaches via predictive analytics and ML for optimizing usage and detecting anomalies in cost.

Ultimately, our goal is to enable our engineering organization to make efficiency-conscious decisions when building and maintaining the myriad of services that allow us to enjoy Netflix as a streaming service.

Acknowledgments

The FPD and CEA work would not have been possible without the cross functional input of many outstanding colleagues and our dedicated team building these important data assets.

—

A bit about the authors:

JHan enjoys nature, reading fantasy, and finding the best chocolate chip cookies and cinnamon rolls. She is adamant about writing the SQL select statement with leading commas.

Pallavi enjoys music, travel and watching astrophysics documentaries. With 15+ years working with data, she knows everything’s better with a dash of analytics and a cup of coffee!


Cloud Efficiency at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Title Launch Observability at Netflix Scale

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/title-launch-observability-at-netflix-scale-c88c586629eb

Part 1: Understanding The Challenges

By: Varun Khaitan

With special thanks to my stunning colleagues: Mallika Rao, Esmir Mesic, Hugo Marques

Introduction

At Netflix, we manage over a thousand global content launches each month, backed by billions of dollars in annual investment. Ensuring the success and discoverability of each title across our platform is a top priority, as we aim to connect every story with the right audience to delight our members. To achieve this, we are committed to building robust systems that deliver comprehensive observability, enabling us to take full accountability for every title on our service.

The Challenge of Title Launch Observability

As engineers, we’re wired to track system metrics like error rates, latencies, and CPU utilization — but what about metrics that matter to a title’s success?

Consider the following example of two different Netflix Homepages:

Sample Homepage A
Sample Homepage B

To a basic recommendation system, the two sample pages might appear equivalent as long as the viewer watches the top title. Yet, these pages couldn’t be more different. Each title represents countless hours of effort and creativity, and our systems need to honor that uniqueness.

How do we bridge this gap? How can we design systems that recognize these nuances and empower every title to shine and bring joy to our members?

The Operational Needs of a Personalization System

In the early days of Netflix Originals, our launch team would huddle together at midnight, manually verifying that titles appeared in all the right places. While this hands-on approach worked for a handful of titles, it quickly became clear that it couldn’t scale. As Netflix expanded globally and the volume of title launches skyrocketed, the operational challenges of maintaining this manual process became undeniable.

Operating a personalization system for a global streaming service involves addressing numerous inquiries about why certain titles appear or fail to appear at specific times and places.
Some examples:

  • Why is title X not showing on the Coming Soon row for a particular member?
  • Why is title Y missing from the search page in Brazil?
  • Is title Z being displayed correctly in all product experiences as intended?

As Netflix scaled, we faced the mounting challenge of providing accurate, timely answers to increasingly complex queries about title performance and discoverability. This led to a suite of fragmented scripts, runbooks, and ad hoc solutions scattered across teams — an approach that was neither sustainable nor efficient.

The stakes are even higher when ensuring every title launches flawlessly. Metadata and assets must be correctly configured, data must flow seamlessly, microservices must process titles without error, and algorithms must function as intended. The complexity of these operational demands underscored the urgent need for a scalable solution.

Automating the Operations

It becomes evident over time that we need to automate our operations to scale with the business. As we thought more about this problem and possible solutions, two clear options emerged.

Option 1: Log Processing

Log processing offers a straightforward solution for monitoring and analyzing title launches. By logging all titles as they are displayed, we can process these logs to identify anomalies and gain insights into system performance. This approach provides a few advantages:

  1. Low burden on existing systems: Log processing imposes minimal changes to existing infrastructure. By leveraging logs, which are already generated during regular operations, we can scale observability without significant system modifications. This allows us to focus on data analysis and problem-solving rather than managing complex system changes.
  2. Using the source of truth: Logs serve as a reliable “source of truth” by providing a comprehensive record of system events. They allow us to verify whether titles are presented as intended and investigate any discrepancies. This capability is crucial for ensuring our recommendation systems and user interfaces function correctly, supporting successful title launches.

However, taking this approach also presents several challenges:

  1. Catching Issues Ahead of Time: Logging primarily addresses post-launch scenarios, as logs are generated only after titles are shown to members. To detect issues proactively, we need to simulate traffic and predict system behavior in advance. Once artificial traffic is generated, discarding the response object and relying solely on logs becomes inefficient.
  2. Appropriate Accuracy: Comprehensive logging requires services to log both included and excluded titles, along with reasons for exclusion. This could lead to an exponential increase in logged data. Utilizing probabilistic logging methods could compromise accuracy, making it difficult to ascertain whether a title’s absence in logs is due to exclusion or random chance.
  3. SLA and Cost Considerations: Our existing online logging systems do not natively support logging at the title granularity level. While reengineering these systems to accommodate this additional axis is possible, it would entail increased costs. Additionally, the time-sensitive nature of these investigations precludes the use of cold storage, which cannot meet the stringent SLAs required.

Option 2: Observability Endpoints in Our Personalization Systems

To prioritize title launch observability, we could adopt a centralized approach. By introducing observability endpoints across all systems, we can enable real-time data flow into a dedicated microservice for title launch observability. This approach embeds observability directly into the very fabric of services managing title launches and personalization, ensuring seamless monitoring and insights. Key benefits and strategies include:

  1. Real-Time Monitoring: Observability endpoints enable real-time monitoring of system performance and title placements, allowing us to detect and address issues as they arise.
  2. Proactive Issue Detection: By simulating future traffic(an aspect we call “time travel”) and capturing system responses ahead of time, we can preemptively identify potential issues before they impact our members or the business.
  3. Enhanced Accuracy: Observability endpoints provide precise data on title inclusions and exclusions, allowing us to make accurate assertions about system behavior and title visibility. It also provides us with advanced debugability information needed to fix identified issues.
  4. Scalability and Cost Efficiency: While initial implementation required some investment, this approach ultimately offers a scalable and cost-effective solution to managing title launches at Netflix scale.

Choosing this option also comes with some tradeoffs:

  1. Significant Initial Investment: Several systems would need to create new endpoints and refactor their codebases to adopt this new method of prioritizing launches.
  2. Synchronization Risk: There would be a potential risk that these new endpoints may not accurately represent production behavior, thus necessitating conscious efforts to ensure all endpoints remain synchronized.

Up Next

By adopting a comprehensive observability strategy that includes real-time monitoring, proactive issue detection, and source of truth reconciliation, we’ve significantly enhanced our ability to ensure the successful launch and discovery of titles across Netflix, enriching the global viewing experience for our members. In the next part of this series, we’ll dive into how we achieved this, sharing key technical insights and details.

Stay tuned for a closer look at the innovation behind the scenes!


Title Launch Observability at Netflix Scale was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Как се съсипва квартал

Post Syndicated from original https://www.toest.bg/kak-se-sasipva-kvartal/

Как се съсипва квартал

Българските градове срещат типичните проблеми на икономическия растеж. Хората започват да пътуват повече и предпочитат това да става по-удобно, с лично превозно средство, за по-кратко време. Притежаването и ползването на автомобил става по-лесно и много семейства започват дори да трупат по две-три и повече леки коли. Степента на моторизация се увеличава, тоест на глава от населението се падат повече автомобили, а ниската им цена също допринася за това увеличение. Отговорът на градовете ни често е да се създаде нова инфраструктура, която обаче невинаги е добре обмислена. И резултатът влошава, вместо да подобрява не само транспортната обстановка, а и цялостното качество на живот. 

Точно такъв е случаят с пробива „Модър“ – „Царевец“ и съпътстващия ремонт на ул. „Царевец“ и бул. „Хаджи Димитър“, които разсичат на две места пловдивския квартал „Христо Смирненски“.

Контекст

Когато придвижването в един град се осъществява само с автомобил, задръстванията неизменно стават ежедневие, допълнени от замърсен въздух и висока концентрация на катастрофи и съответно – на ранени и загинали. Градски площади, градинки, междублокови пространства биват лека-полека замествани от паркирали коли. Зелени площи се превръщат в кална кочина, а след геройската намеса на Общината след няколко години се заливат с асфалт и се превръщат в обикновени паркоместа. От зеленината няма и помен. Това е най-лошият пример за ползване на едно открито публично пространство – да стане склад на превозни средства вместо парк например, където млади и стари да прекарват време, да се срещат с приятели, да спортуват, да се разхождат с децата. 

Осигуряването на паркоместа не е лоша дейност – лошо е, ако един град няма адекватна съвременна транспортна политика, с която да прави придвижването с градски транспорт удобно, комфортно и модерно, за да не се налага всеки за всяко нещо да сяда в колата и да търси след това паркомясто. 

В случая с Пловдив проблемът с автомобилите е особено значителен, понеже общественият транспорт е оставен на финални издихания.

Много малко хора разчитат на него и придвижванията с автомобил преобладават, съответно и задръстванията. 

В големи и малки градове по целия свят, в които транспортът се управлява успешно и които са се справили със задръстванията, се знае, че развитието на удобен градски транспорт е истинското дълготрайно решение. Тази стъпка е незаобиколима – това урбанистите и транспортните инженери го учат още в началните курсове по транспортно планиране. Един автобус с 50 места замества десетки автомобили – това следва от данните, посочени в Плана за устойчива градска мобилност (ПУГМ) на община Пловдив, според които в 44% от колите в града пътува само един човек. 

Тази проста сметка показва как използването на масов транспорт може да разреши проблема със задръстванията, стига този транспорт да е наличен, да е с удобни и директни маршрути между кварталите, да е начесто, превозните средства да са комфортни, да може да се заплаща билет по съвременни начини и да е популярен сред гражданите. 

Липсващата транспортна политика на Пловдив

Незнайно защо Пловдив не гледа към София или Бургас като градове с функциониращ градски транспорт. Реформа в управлението на транспорта в Града под тепетата така и не се прави. Единствените мерки, които се обявяват за „транспортни“, са свързани с преасфалтиране и изграждане на нови автомобилни участъци. Пловдив действително има нужда от доизграждане на няколко ключови връзки, които и до момента липсват. Затова е положително развитие, че пробивът „Модър“ – „Царевец“ се реализира след години на подготовка и обещания. 

Редно е обаче такива проекти да се впишат в по-голямата картина и транспортна политика на града. ПУГМ на Пловдив беше приет през 2024 г. Целта му е да намали автомобилната зависимост на града и да допринесе за развитието на устойчиви форми на придвижване – градски транспорт, велосипедна и пешеходна мобилност. Предложените мерки следва да се структурират и приложат по приоритетност. 

Едно от изискванията към изпълнителя на ПУГМ беше да се създаде дигитален транспортен модел на града. Такива модели се ползват от десетилетия от по-иновативните градски власти, за да се тества как една мярка ще се отрази на транспортната ситуация – например ако се затвори улица, ако се изгради нова транспортна връзка, ако се обособи буслента, ако се направи трамвайна линия или метро, ако се регламентира паркирането. Всичко това се вижда в дигитална среда, преди да е похарчен и един лев за строителство. ПУГМ на Пловдив е предаден и се очаква в общината да е наличен функциониращ такъв модел. Дали наистина обаче той е реализиран и дали изобщо се ползва?

Пробивът „Модър“ – „Царевец“

Пробивът „Модър“ – „Царевец“ поставя под сериозно съмнение наличието на дигитален транспортен модел на Пловдив. Начинът на реализация на този проект повдига въпроса дори дали е правено някакво транспортно проучване на преминаващите и посоката на тяхното движение, на основата на което да се предложат най-добрият проект и най-адекватната организация на движение.

Общината се похвали с отварянето на кръстовището на ул. „Царевец“ с ул. „Солунска“ и го представи като успех. На практика обаче новият светофар работи напразно, тъй като движението е възможно само в една посока, а другата част от ул. „Царевец“ е все още в ремонт. Светофарът доведе до безпрецедентни задръствания.

След месеци чакане и тестване на търпението на хората те всъщност се оказаха в по-лоша ситуация, отколкото преди това.

Ако след приключването на ремонта автомобилният трафик в района се увеличи, няма изгледи проблемът със задръстванията да се реши. Той можеше да се облекчи, ако беше изградено кръгово кръстовище, каквото обаче не е предвидено.

Когато се влагат обществени средства и се отделят месеци, а понякога дори години за ремонтни дейности по определени участъци, които нарушават нормалното ежедневие на гражданите, създават задръствания и губят ценно време, е напълно основателно да се поставят под въпрос ефективността и обосновката на целия проект. Още повече ако в крайна сметка ремонтните дейности водят до по-лоша транспортна ситуация от предишната, следва да се анализира как се е стигнало до неговото одобрение.

Да се изхарчат милиони, да се наруши градският ритъм на хиляди хора и накрая да се влоши качеството им на живот не е символ на добро управление.

Подобен светофар беше инсталиран преди няколко месеца на бул. „Хаджи Димитър“. Той създаде задръстване там, където преди нямаше. Съвсем релевантен е въпросът защо се поставят светофари на места, където пречат и влошават пътната обстановка. 

Параметърът „пропускливост“ е основополагащ в транспортното планиране. Редно е преминаващите през едно кръстовище превозни средства да се преброят предварително, а след това да се изготви проект, който да подобри пропускливостта. Случаят с бул. „Хаджи Димитър“ е пример за влошаване на ситуацията, а новото му кръстовище с ул. „Царевец“ явно ще е със същия резултат. 

Какво не е град за хората?

В книгата си „Градове за хората“ датският урбанист Ян Геел застъпва идеята, че хората, а не автомобилите следва да са в центъра на градския живот и съответно – в основата на градското планиране. А това означава и по-силен акцент върху придвижването пеша и с колело. Ян Геел беше в Пловдив през 2016 г. при представянето на превода на книгата си на български език по време на фестивала One Architecture Week.

Следвайки политиките за устойчива мобилност, в „градовете за хората“ се приоритизират пешеходните и велосипедните маршрути, като се създава мрежа от свързани отсечки и се осигуряват възможности за често пресичане на големи булеварди. Целта е постепенно пешеходецът да се постави на приоритетна позиция спрямо автомобила. 

Пловдив е град с изключително висока концентрация на пътнотранспортни произшествия, което не говори добре за прилаганите до момента мерки за пътна безопасност. Именно чрез проектиране на градска среда и транспортна инфраструктура, които приоритизират уязвимите участници, може да се постигне по-безопасна, а и по-приятна среда за всички – с повече качествени улични пространства. 

Проектите за бул. „Хаджи Димитър“ и ул. „Царевец“ са пример за тотално остаряла концепция,

която се отхвърля от десетилетия от урбанистите и транспортните инженери, работещи за качествена градска среда. Булевард „Хаджи Димитър“ преминава през гъсто застроената част на квартала, която е без открити паркове или площади. Самият булевард включва пешеходна алея по средата именно за да позволи на живеещите в близост да използват това място за отдих и възстановяване – като малък линеен парк близо до техните домове. Обновеният булевард се изгражда с огради по средата, все едно е магистрала в полето, а не част от градската среда. Достъпът до линейния парк е възможен от по-малко места, отколкото преди. По този начин кв. „Христо Смирненски“ се разсече, а пешеходните връзки, вместо да се регламентират с пресичания, да се направят удобни и безопасни, да се улесни достъпът до този линеен парк, бяха почти изцяло прекъснати. 

Такива реализации също допринасят за увеличаването на задръстванията, защото, когато на хората се създадат затруднения да се движат пеш в квартала, им се налага да ползват автомобили дори и за кратки разстояния. Ала и този урок е научен от много градове.

На Пловдив не му е нужно да открива топлата вода, а да смени кранчето.

Каква се очаква да бъде обновената улица „Царевец“?

От улица с богато улично озеленяване, изключително важно за град като Пловдив – с високи температури и малко паркове, ул. „Царевец“ се превръща в магистрала, разрязваща още един път квартала и влошаваща пешеходната му свързаност. Тъй като публичността е основен принцип на доброто управление, редно е Община Пловдив да отговори на следните въпроси: 

  • Взети ли са под внимание предложенията на гражданите за обновяването на конкретните отсечки, обхванати от проекта? 
  • Разработени ли са различни проектни сценарии за най-адекватно решение? 
  • Правено ли е предварително транспортно проучване и ако да, къде е то? 
  • Налице ли е изобщо процес на ангажиране на местната общност? 
  • Проектът публикуван ли е някъде, или се работи на сляпо и гражданите ще видят резултата, след като строежът приключи?

Инсталирането на светофари там, където няма нужда от тях и където създават повече проблеми, отколкото помагат, е грешка, която може да бъде поправена с премахването им. По-големите въпроси обаче изискват по-големи решения – създаването и следването на съвременна транспортна политика, организация на движението, която дава приоритет на хората, изграждането на инфраструктура, която се грижи за комфорта и безопасността на гражданите, и развитието на обществен транспорт, адекватен за половинмилионен град.


В настоящата ни съвместна поредица с „Екипът на София“ обсъждаме планирането, озеленяването, архитектурата, инфраструктурата, мобилността и още много други градски теми, описваме добрите примери и търсим възможните решения за подобряването на качеството на живот в нашите градове. 

Как се съсипва квартал

Fedora Asahi Remix 41 is now available

Post Syndicated from jzb original https://lwn.net/Articles/1002546/

Fedora Magazine reports
that the Fedora Asahi Remix 41 for Apple Silicon is now available:

In addition to all the exciting improvements brought by Fedora Linux
41, Fedora Asahi Remix 41 provides x86/x86-64
emulation
integration including support for AAA
games
to Apple Silicon. The game support is based on the new
conformant Vulkan
1.4
driver. It also continues to provide extensive device support,
including high quality audio out of the box.

LWN covered a talk
from the X.org Developers Conference (XDC) by Alyssa Rosenzweig on the
status of Asahi’s GPU drivers in October.

Recap of Amazon Redshift key product announcements in 2024

Post Syndicated from Neeraja Rentachintala original https://aws.amazon.com/blogs/big-data/recap-of-amazon-redshift-key-product-announcements-in-2024/

Amazon Redshift, launched in 2013, has undergone significant evolution since its inception, allowing customers to expand the horizons of data warehousing and SQL analytics. Today, Amazon Redshift is used by customers across all industries for a variety of use cases, including data warehouse migration and modernization, near real-time analytics, self-service analytics, data lake analytics, machine learning (ML), and data monetization.

Amazon Redshift made significant strides in 2024, rolling out over 100 features and enhancements. These improvements enhanced price-performance, enabled data lakehouse architectures by blurring the boundaries between data lakes and data warehouses, simplified ingestion and accelerated near real-time analytics, and incorporated generative AI capabilities to build natural language-based applications and boost user productivity.

2024 Redshift announcements summary

Figure1: Summary of the features and enhancements in 2024

Let’s walk through some of the recent key launches, including the new announcements at AWS re:Invent 2024.

Industry-leading price-performance

Amazon Redshift offers up to three times better price-performance than alternative cloud data warehouses. Amazon Redshift scales linearly with the number of users and volume of data, making it an ideal solution for both growing businesses and enterprises. For example, dashboarding applications are a very common use case in Redshift customer environments where there is high concurrency and queries require quick, low-latency responses. In these scenarios, Amazon Redshift offers up to seven times better throughput per dollar than alternative cloud data warehouses, demonstrating its exceptional value and predictable costs.

Performance improvements

Over the past few months, we have introduced a number of performance improvements to Redshift. First query response times for dashboard queries have significantly improved by optimizing code execution and reducing compilation overhead. We have enhanced data sharing performance with improved metadata handling, resulting in data sharing first query execution that is up to four times faster when the data sharing producer’s data is being updated. We have enhanced autonomics algorithms to generate and implement smarter and quicker optimal data layout recommendations for distribution and sort keys, further optimizing performance. We have launched new RA3.large instances, a new smaller size RA3 node type, to offer better flexibility in price-performance and provide a cost-effective migration option for customers using DC2.large instances. Additionally, we have rolled out AWS Graviton in Serverless, offering up to 30% better price-performance, and expanded concurrency scaling to support more types of write queries, enabling an even greater ability to maintain consistent performance at scale. These improvements collectively reinforce Amazon Redshift’s focus as a leading cloud data warehouse solution, offering unparalleled performance and value to customers.

General availability of multi-data warehouse writes

Amazon Redshift allows you to seamlessly scale with multi-cluster deployments. With the introduction of RA3 nodes with managed storage in 2019, customers obtained flexibility to scale and pay for compute and storage independently. Redshift data sharing, launched in 2020, enabled seamless cross-account and cross-Region data collaboration and live access without physically moving the data, while maintaining transactional consistency. This allowed customers to scale read analytics workloads and offered isolation to help maintain SLAs for business-critical applications. At re:Invent 2024, we announced the general availability of multi-data warehouse writes through data sharing for Amazon Redshift RA3 nodes and Serverless. You can now start writing to shared Redshift databases from multiple Redshift data warehouses in just a few clicks. The written data is available to all the data warehouses as soon as it’s committed. This allows your teams to flexibly scale write workloads such as extract, transform, and load (ETL) and data processing by adding compute resources of different types and sizes based on individual workloads’ price-performance requirements, as well as securely collaborate with other teams on live data for use cases such as customer 360.

General availability of AI-driven scaling and optimizations

The launch of Amazon Redshift Serverless in 2021 marked a significant shift, eliminating the need for cluster management while paying for what you use. Redshift Serverless and data sharing enabled customers to easily implement distributed multi-cluster architectures for scaling analytics workloads. In 2024, we launched Serverless in 10 more regions, improved functionality, and added support for a capacity configuration of 1024 RPUs, allowing you to bring larger workloads onto Redshift. Redshift Serverless is also now even more intelligent and dynamic with the new AI-driven scaling and optimization capabilities. As a customer, you choose whether you want to optimize your workloads for cost, performance, or keep it balanced, and that’s it. Redshift Serverless works behind the scenes to scale the compute up and down and deploys optimizations to meet and maintain the performance levels, even when workload demands change. In internal tests, AI-driven scaling and optimizations showcased up to 10 times price-performance improvements for variable workloads.

Seamless Lakehouse architectures

Lakehouse brings together flexibility and openness of data lakes with the performance and transactional capabilities of data warehouses. Lakehouse allows you to use preferred analytics engines and AI models of your choice with consistent governance across all your data. At re:Invent 2024, we unveiled the next generation of Amazon SageMaker, a unified platform for data, analytics, and AI. This launch brings together widely adopted AWS ML and analytics capabilities, providing an integrated experience for analytics and AI with a re-imagined lakehouse and built-in governance.

General availability of Amazon SageMaker Lakehouse

Amazon SageMaker Lakehouse unifies your data across Amazon S3 data lakes and Redshift data warehouses, enabling you to build powerful analytics and AI/ML applications on a single copy of data. SageMaker Lakehouse provides the flexibility to access and query your data using Apache Iceberg open standards so that you can use your preferred AWS, open source, or third-party Iceberg-compatible engines and tools. SageMaker Lakehouse offers integrated access controls and fine-grained permissions that are consistently applied across all analytics engines and AI models and tools. Existing Redshift data warehouses can be made available through SageMaker Lakehouse in just a simple publish step, opening up all your data warehouse data with Iceberg REST API. You can also create new data lake tables using Redshift Managed Storage (RMS) as a native storage option. Check out the Amazon SageMaker Lakehouse: Accelerate analytics & AI presented at re:Invent 2024.

Preview of Amazon SageMaker Unified Studio

Amazon SageMaker Unified Studio is an integrated data and AI development environment that enables collaboration and helps teams build data products faster. SageMaker Unified Studio brings together functionality and tools from a mix of standalone studios, query editors, and visual tools available today in Amazon EMR, AWS Glue, Amazon Redshift, Amazon Bedrock, and the existing Amazon SageMaker Studio, into one unified experience. With SageMaker Unified Studio, various users such as developers, analysts, data scientists, and business stakeholders can seamlessly work together, share resources, perform analytics, and build and iterate on models, fostering a streamlined and efficient analytics and AI journey.

Amazon Redshift SQL analytics on Amazon S3 Tables

At re:Invent 2024, Amazon S3 introduced Amazon S3 Tables, a new bucket type that is purpose-built to store tabular data at scale with built-in Iceberg support. With table buckets, you can quickly create tables and set up table-level permissions to manage access to your data lake. Amazon Redshift introduced support for querying Iceberg data in data lakes last year, and now this capability is extended to seamlessly querying S3 Tables. S3 Tables customers create are also available as part of the Lakehouse for consumption by other AWS and third-party engines.

Data lake query performance

Amazon Redshift offers high-performance SQL capabilities on SageMaker Lakehouse, whether the data is in other Redshift warehouses or in open formats. We enhanced support for querying Apache Iceberg data and improved the performance of querying Iceberg up to threefold year-over-year. A number of optimizations contribute to these speed-ups in performance, including integration with AWS Glue Data Catalog statistics, improved data and metadata filtering, dynamic partition elimination, faster/parallel processing of Iceberg manifest files, and scanner improvements. In addition, Amazon Redshift now supports incremental refresh support for materialized views on data lake tables to eliminate the need for recomputing the materialized view when new data arrives, simplifying how you build interactive applications on S3 data lakes.

Simplified ingestion and near real-time analytics

In this section, we share the improvements regarding simplified ingestion and near real-time analytics that enable you to get faster insights over fresher data.

Zero-ETL integration with AWS databases and third-party enterprise applications

Amazon Redshift first launched zero-ETL integration between Amazon Aurora MySQL-Compatible Edition, enabling near real-time analytics on petabytes of transactional data from Aurora. This capability has since expanded to support Amazon Aurora PostgreSQL-Compatible Edition, Amazon Relational Database Service (Amazon RDS) for MySQL, and Amazon DynamoDB, and includes additional features such as data filtering to selectively extract tables and schemas using regular expressions, support for incremental and auto-refresh materialized views on replicated data, and configurable change data capture (CDC) refresh rates.

Building on this innovation, at re:Invent 2024, we launched support for zero-ETL integration with eight enterprise applications, specifically Salesforce, Zendesk, ServiceNow, SAP, Facebook Ads, Instagram Ads, Pardot, and Zoho CRM. With this new capability, you can efficiently extract and load valuable data from your customer support, relationship management, and Enterprise Resource Planning (ERP) applications directly into your Redshift data warehouse for analysis. This seamless integration eliminates the need for complex, custom ingestion pipelines for ingesting the data, accelerating time to insights.

General availability of auto-copy

Auto-copy simplifies data ingestion from Amazon S3 into Amazon Redshift. This new feature enables you to set up continuous file ingestion from your Amazon S3 prefix and automatically load new files to tables in your Redshift data warehouse without the need for additional tools or custom solutions.

Streaming ingestion from Confluent Managed Cloud and self-managed Apache Kafka clusters

Amazon Redshift now supports streaming ingestion from Confluent Managed Cloud and self-managed Apache Kafka clusters on Amazon EC2instances, expanding its capabilities beyond Amazon Kinesis Data Streams and Amazon Managed Streaming for Apache Kafka (Amazon MSK). With this update, you can ingest data from a wider range of streaming sources directly into your Redshift data warehouses for near real-time analytics use cases such as fraud detection, logistics monitoring and clickstream analysis.

Generative AI capabilities

In this section, we share the improvements generative AI capabilities.

Amazon Q generative SQL for Amazon Redshift

We announced the general availability of Amazon Q generative SQL for Amazon Redshift feature in the Redshift Query Editor. Amazon Q generative SQL boosts productivity by allowing users to express queries in natural language and receive SQL code recommendations based on their intent, query patterns, and schema metadata. The conversational interface enables users to get insights faster without extensive knowledge of the database schema. It leverages generative AI to analyze user input, query history, and custom context like table/column descriptions and sample queries to provide more relevant and accurate SQL recommendations. This feature accelerates the query authoring process and reduces the time required to derive actionable data insights.

Amazon Redshift integration with Amazon Bedrock

We announced integration of Amazon Redshift with Amazon Bedrock, enabling you to invoke large language models (LLMs) from simple SQL commands on your data in Amazon Redshift. With this new feature, you can now effortlessly perform generative AI tasks such as language translation, text generation, summarization, customer classification, and sentiment analysis on your Redshift data using popular foundation models (FMs) like Anthropic’s Claude, Amazon Titan, Meta’s Llama 2, and Mistral AI. You can invoke these models using familiar SQL commands, making it simpler than ever to integrate generative AI capabilities into your data analytics workflows.

Amazon Redshift as a knowledge base in Amazon Bedrock

Amazon Bedrock Knowledge Bases now supports natural language querying to retrieve structured data from your Redshift data warehouses. Using advanced natural language processing, Amazon Bedrock Knowledge Bases can transform natural language queries into SQL queries, allowing users to retrieve data directly from the source without the need to move or preprocess the data. A retail analyst can now simply ask “What were my top 5 selling products last month?”, and Amazon Bedrock Knowledge Bases automatically translates that query into SQL, runs the query against Redshift, and returns the results—or even provides a summarized narrative response. To generate accurate SQL queries, Amazon Bedrock Knowledge Bases uses database schema, previous query history, and other contextual information that is provided about the data sources.

Launch summary

Following is the launch summary which provides the announcement links and reference blogs for the key announcements.

Industry-leading price-performance:

Reference Blogs:

Seamless Lakehouse architectures:

Reference Blogs:

Simplified ingestion and near real-time analytics:

Reference Blogs:

Generative AI:

Reference Blogs:

Conclusion

We continue to innovate and evolve Amazon Redshift to meet your evolving data analytics needs. We encourage you to try out the latest features and capabilities. Watch the Innovations in AWS analytics: Data warehousing and SQL analytics session from re:Invent 2024 for further details. If you need any support, reach out to us. We are happy to provide architectural and design guidance, as well as support for proof of concepts and implementation. It’s Day 1!


About the Author

Neeraja Rentachintala is Director, Product Management with AWS Analytics, leading Amazon Redshift and Amazon SageMaker Lakehouse. Neeraja is a seasoned technology leader, bringing over 25 years of experience in product vision, strategy, and leadership roles in data products and platforms. She has delivered products in analytics, databases, data integration, application integration, AI/ML, and large-scale distributed systems across on-premises and the cloud, serving Fortune 500 companies as part of ventures including MapR (acquired by HPE), Microsoft SQL Server, Oracle, Informatica, and Expedia.com

The collective thoughts of the interwebz