Post Syndicated from Explosm.net original https://explosm.net/comics/to-go-box
New Cyanide and Happiness Comic
Post Syndicated from Explosm.net original https://explosm.net/comics/to-go-box
New Cyanide and Happiness Comic
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/08/friday-squid-blogging-self-healing-materials-from-squid-teeth.html
Making self-healing materials based on the teeth in squid suckers.
Post Syndicated from Muhammad Shahzad original https://aws.amazon.com/blogs/devops/publish-packages-to-aws-codeartifact-using-amazon-codecatalyst-actions/
Amazon CodeCatalyst is a unified software development service for development teams to quickly build, deliver and scale applications on AWS while adhering to organization-specific best practices. Developers can automate development tasks and innovate faster with generative AI capabilities, and spend less time setting up project tools, managing CI/CD pipelines, provisioning and configuring various development environments or coordinating with team members.
It can integrate with services like AWS CodeArtifact, which is a managed artifact repository service that lets you securely store, publish, and share software packages. In this blog post we will show you how to use Publish to AWS CodeArtifact action in a CodeCatalyst workflow to publish packages to AWS Code Artifact.
In Amazon CodeCatalyst, an action is the main building block of a workflow, and defines a logical unit of work to perform during a workflow run. Typically, a workflow includes multiple actions that run sequentially or in parallel depending on how you’ve configured them. Amazon CodeCatalyst provides a library of pre-built actions that you can use in your workflows, such as for building, testing, deploying applications, as well as the ability to create custom actions for specific tasks not covered by the pre-built options.
Following are the instructions on using Publish to AWS CodeArtifact action in Amazon CodeCatalyst workflow.
To follow along with this walkthrough, you will need:
And the following custom trust policy.
In the trust policy, we have specified two AWS services in the Principal element. Service principals are defined by the service. The following service principals are defined for CodeCatalyst:
In this example, we are going to publish a npm package to a CodeArtifact repository called ‘myapp-frontend in the domain ‘myapp-artifacts. Amazon CodeCatalyst is available in two regions at the moment i.e. Europe (Ireland) and US West (Oregon). We will use ‘us-west-2’ for all the resources in this walkthrough.
Here are the steps to create your workflow.
The workflow definition file appears in the CodeCatalyst console’s YAML editor.
To configure your workflow
You can configure your workflow in the Visual editor, or the YAML editor. Let’s start with the YAML editor and then switch to the visual editor.

The following code shows the newly created workflow.
In this build action, we are using ‘npm pack’ command to create a compressed tarball (.tgz) file of our package’s source code and configuration files. We are creating an output artifact named ‘ARTIFACT’ and our files are in this directory integration/npm/npm-package-example-master.
Now, we are going to select publish-to-code-artifact action from the action’s dropdown list.

The following code shows the newly added action in the workflow file.
In the above code, you can see we specified the PackageFormat, RepositoryName, DomainName and AWSRegion.These are all required fields.
For Package Path, it is the build artifact output path + the folder path.
You can find the complete workflow file in this GitHub repository.
If you chose ‘Visual’ option to view the workflow definition file in the visual editor. This is going to look as shown in the image below. The fields in the visual editor let you configure the YAML properties shown in the YAML editor.

The “Publish to AWS CodeArtifact” action works as follows at runtime:
If you have been following along with this workflow, you should delete the resources you deployed so that you do not continue to incur charges.
In this post, we demonstrated how to use an Amazon CodeCatalyst workflow to publish packages to AWS CodeArtifact by utilizing the Publish to AWS CodeArtifact action. By following the steps outlined in this blog post, you can ensure that your packages are readily available for your projects while maintaining version control and security.
For further reading, see Working with actions in the CodeCatalyst documentation.

Muhammad Shahzad is a Solutions Architect at AWS. He is passionate about helping customers achieve success on their cloud journeys, enjoys designing solutions and helping them implement DevSecOps by explaining principles, creating automated solutions and integrating best practices in their journey to the cloud. Outside of work, Muhammad plays badminton regularly, enjoys various other sports, and has a passion for hiking scenic trails.
 Alexander Schueren is a Senior Specialist Solutions Architect at AWS, dedicated to modernizing legacy applications and building event-driven serverless solutions. With a focus on simplifying complexity and bringing clarity to technical challenges, Alexander is on a mission to empower developers with the tools they need for success. As the maintainer of the open-source project “Powertools for AWS Lambda (TypeScript),” he is committed to driving innovation in serverless technologies. In his free time, Alexander channels his creativity through street photography, capturing decisive moments in the urban landscape.
Post Syndicated from Eric Smith original https://www.servethehome.com/minisforum-deg1-oculink-egpu-dock-quick-look-amd-nvidia/
We take a quick look at the Minisforum DEG1 Oculink eGPU dock that we will be using in two forthcoming system reviews
The post Minisforum DEG1 Oculink eGPU Dock Quick Look appeared first on ServeTheHome.
Post Syndicated from Geographics original https://www.youtube.com/watch?v=87wj5AJjaAY
Post Syndicated from Alan David Foster original https://blog.rapid7.com/2024/08/23/metasploit-weekly-wrap-up-08-23-2024/
Authors: Michael Heinzl and Tenable
Type: Auxiliary
Pull request: #19373 contributed by h4x-x0r
Path: admin/http/fortra_filecatalyst_workflow_sqli
AttackerKB reference: CVE-2024-5276
Description: This adds an auxiliary module to exploit the CVE-2024-5276, a SQL injection vulnerability that allows for adding an arbitrary administration user in the application.
Authors: Julien Voisin, Laluka, and Valentin Lobstein
Type: Exploit
Pull request: #19394 contributed by Chocapikk
Path: multi/http/spip_porte_plume_previsu_rce
Description: Adds a new exploit/multi/http/spip_porte_plume_previsu_rce SPIP unauthenticated remote code execution (RCE) module targeting SPIP versions up to and including 4.2.12.
Authors: Michael Heinzl and Tenable
Type: Exploit
Pull request: #19351 contributed by h4x-x0r
Path: windows/scada/diaenergie_sqli
AttackerKB reference: CVE-2024-4548
Description: This adds an exploit module for CVE-2024-4548, an unauthenticated SQL injection vulnerability that allows remote code execution as NT AUTHORITY\SYSTEM.
You can find the latest Metasploit documentation on our docsite at docs.metasploit.com.
As always, you can update to the latest Metasploit Framework with msfupdate and you can get more details on the changes since the last blog post from GitHub:
If you are a git user, you can clone the Metasploit Framework repo (master branch) for the latest.
To install fresh without using git, you can use the open-source-only Nightly Installers or the
commercial edition Metasploit Pro
Post Syndicated from João Tomé original https://blog.cloudflare.com/internet-security-trends-2024-us-democratic-convention
The 2024 Democratic National Convention (DNC) wrapped up on Thursday, August 22, in Chicago, Illinois. Since our blog post about Internet trends during the first presidential debate between President Joe Biden and former President Donald Trump on June 27, the presidential race has fundamentally changed. We experienced the attempted assassination of Trump, the Republican National Convention (RNC), Biden’s late July withdrawal from the race, and Vice President Kamala Harris being selected as the Democratic nominee and participating in her party’s convention this week. Here, we’ll examine trends more focused on DNS traffic to news and candidate-related sites, cyberattacks targeting politically-related organizations, and spam and malicious emails mentioning the candidates’ names.
Over 60 more national elections are scheduled to take place across the world this year, and we have been monitoring them as they occur. Our goal is to provide a neutral analysis of their impact on Internet behavior, which often mirrors human activities. Significant events, such as the total eclipse in Mexico, the United States, and Canada, and the Paris 2024 Olympics, have had an impact on Internet traffic. Our ongoing election report on Cloudflare Radar includes updates from recent elections in the European Union, France, and the United Kingdom.
Let’s start with an Internet traffic perspective on the Chicago area, where the Democratic National Convention took place from August 19 through August 22, 2024.
Internet traffic shifts during major events like elections – and there have been several this year – are typically more impactful than those from a single political party’s event. During the DNC in Chicago, Illinois, we didn’t observe an obvious pattern change, similar to the RNC that took place in Milwaukee, Wisconsin in June.
Throughout the convention, although we didn’t notice any significant drops or spikes in Chicago’s Internet traffic, there was a rise in traffic starting on August 15 and continuing through the first three days of the convention. Notably, traffic was 10% to 20% higher after midnight compared to the previous week.
Shifting our focus to domain trends, our 1.1.1.1 resolver data highlights a more targeted impact from the DNC and preceding weeks. This analysis now includes Kamala Harris-related insights, as our earlier reports on the Biden-Trump debate and the Republican National Convention predated her selection as the Democratic nominee.
Kamala Harris’s official website, initially redirecting to Joe Biden’s website, became an independent dedicated site after July 21, following Biden’s announcement of his withdrawal and endorsement of Harris. Since then, aggregated daily DNS traffic to Kamala Harris-related domains has seen significant growth, particularly after June 29.
On August 6, the day Kamala Harris selected Minnesota Governor Tim Walz as her running mate, DNS traffic for Kamala Harris-related domains increased by 99% compared to the previous week. Following this announcement, as Harris and Walz campaigned together in various cities, DNS traffic initially peaked on August 8-9, showing increases of 896% and 845%, respectively. Another significant spike occurred on August 15, which persisted through the DNC, peaking on its fourth day, August 23, with a 21% growth in DNS traffic compared to the previous week.
From an hourly perspective, the impact of the convention on Kamala Harris-related sites is evident, with increased DNS traffic in the evenings coinciding with the convention’s key speakers. Traffic grew each day compared to the day before.
Here’s a summary of peak hourly DNS traffic to Kamala Harris’s-related domains on each day of the DNC, coinciding with key moments of the event:
Day 1, August 19: Peak at 23:00 EDT with a 313% increase in traffic compared to the previous week. This spike occurred around the time President Joe Biden appeared on stage.
Day 2, August 20: Peak at 00:00 EDT (August 21) with a 466% increase, following former President Barack Obama’s speech that closed the second day of the DNC.
Day 3, August 21: Peak at 22:00 EDT with a 70% increase just before Governor Tim Walz took the stage. Although this peak was higher than previous days, the percentage increase was lower due to higher traffic at the same time the previous week.
Day 4, August 22: Peak at 23:00 EDT with a 71% increase around the time of Vice President Kamala Harris’s speech.
During the DNC, we observed a rise in DNS traffic for Harris/Democrats fundraising domains. The main spike occurred on day 4 of the DNC, August 22, at around 21:00 EDT, with a 493% increase compared to the previous week. On that day, daily traffic increased by 92% compared to the previous week.
Like the RNC before it, the DNC sparked significant interest in US news organizations, resulting in an uptick in aggregated DNS traffic to general US news sites. This increase typically occurred just after the final speaker of the evening.
On day 1 of the DNC, traffic to US news organizations was 11% higher compared to the previous week at 23:00 EDT, coinciding with President Biden’s appearance. On day 2, when President Obama concluded the evening, DNS traffic to US news sites increased by 10%, continuing to rise thereafter. On day 3, during the hour when Vice Presidential candidate Tim Walz spoke, DNS traffic to US news sites spiked by 21% at 23:00 EDT. The final day (day 4) saw a 28% increase at 23:00 EDT, around Vice President Kamala Harris’s speech.
Attacks on political parties have remained a significant threat in an election-filled 2024. In Europe, we’ve seen political parties and associated websites targeted around elections. We previously reported on DDoS attacks around the Republican National Convention, and these types of attacks continued during the weeks ahead of the Democratic National Convention.
Since July 21, 2024, Cloudflare has blocked DDoS attacks targeting three US politically-related organizations. A site associated with one of the major parties (represented by the blue line on the chart) was attacked on July 23, and again just before the DNC.
The largest DDoS attack recorded (indicated in green) targeted another US politically-related website on July 26, peaking at 180,000 requests per second (rps) and lasting about 10 minutes. There were other smaller attacks, earlier on the same day, and on July 28.
Another site, focused on political fundraising, experienced a smaller attack on August 1, also lasting 10 minutes and peaking at 103,000 rps.
The most recent attacks we’ve observed occurred on August 17-18 (UTC time), targeting a politically-related website (blue line) and another politically-related website (green line). The former peaked at 62,000 rps on August 18, while the latter reached 24,000 rps on August 17.
As highlighted in our Q2 DDoS report, most DDoS attacks are short-lived, as exemplified by the two mentioned attacks. Also, 81% of HTTP DDoS attacks peak at under 50,000 requests per second (rps), and only 7% reach between 100,000 and 250,000 rps. While a 24,000 rps attack might seem minor to Cloudflare, it can be devastating for websites not equipped to handle such high levels of traffic.
From another cybersecurity angle, trending events, topics and individuals often attract malicious, phishing, and spam messages, and also more emails in general. Our earlier analysis covered email trends involving “Joe Biden” or “Donald Trump” since January, concluding just after the Biden-Trump debate in late June. From June 1, 2024, through August 21, Cloudflare’s Cloud Email Security service processed around 14 million emails that included the names “Donald Trump”, “Joe Biden”, or “Kamala Harris” in the subject, with 7.4 million referencing Trump.
The next chart highlights a surge in emails mentioning Trump in mid-July, contrasting with a drop of emails mentioning Biden in the subject, who saw a brief uptick on July 22-23 following his withdrawal from the race, and on August 20, the day after his DNC speech.
Focusing on the period since July 21 – when changes in the presumptive Democratic candidate occurred – over 3.2 million emails mentioned “Donald Trump”, around 1.2 million mentioned “Joe Biden”, and over 2 million mentioned “Kamala Harris” in the subject. Examining spam and phishing messages, 34% of emails with Trump’s name were spam, and 3% were malicious. For Kamala Harris, 0.8% were spam and 0.2% were malicious, while Biden’s figures were 1.1% for spam and 0.1% for malicious.
To better understand the elevated percentages of spam and malicious emails mentioning “Donald Trump,” it’s important to look at the trend over time. Notably, after July 15, there was a significant rise in all emails mentioning Trump in the subject, as the previous line chart also shows, and that also included a higher percentage of emails classified as spam.
Additionally, Republican Vice Presidential Candidate JD Vance and Democratic Vice Presidential Candidate Tim Walz also influenced email trends. JD Vance was announced as Donald Trump’s running mate on July 15, so we start there – Tim Walz’s announcement came later, on August 6. Emails with “Tim Walz” mentioned in the subject (over 530,000) outnumbered those with “JD Vance” (over 241,000). Spam made up 1% of emails with Vance’s name and 0.1% were malicious, and for Walz, 0.7% were spam and 0.03% malicious.
In this analysis of the Democratic National Convention, we’ve observed trends similar to those seen during the Republican National Convention. However, with Kamala Harris becoming the Democratic presidential candidate recently, there has been a noticeable increase in DNS traffic to both Kamala Harris-related domains and Democrats’ fundraising domains.
We have also noted that DDoS attacks targeting US politically-related organizations continue, and emails mentioning the candidates in the subject (including spam and malicious emails) have increased.
If you’re interested in more trends and insights about the Internet and elections, check out Cloudflare Radar, specifically our 2024 Elections Insights report. It will be updated throughout the year as elections (or election-related events) occur.
Post Syndicated from jake original https://lwn.net/Articles/985739/
On the second day of DebConf24
in Busan, South Korea, Holger Levsen provided a history lesson on the
“first 11 years” of the Reproducible Builds project.
He has been involved in the project for most of that time and has been a
Debian user since the mid-1990s, contributor since 2001, and a Debian
member since 2007; “I love Debian”. Meanwhile, his aim is to make all free
software be reproducible, so that anyone can check that a binary program
comes from the source code it purports to.
Post Syndicated from daroc original https://lwn.net/Articles/986998/
The
Forgejo project has announced that, starting from version 9.0, Forgejo will be released under the GPLv3 license (or a later version). Older versions of the software forge remain MIT-licensed.
A copyleft license makes reusing other copyleft software easier. Recently, we discovered that
some of the dependencies we used were incompatible with the license Forgejo was distributed with, and they had to be removed for now. Choosing copyleft licenses enables us to reuse more work, and saves us precious time to focus on improving Forgejo itself.
Post Syndicated from Explosm.net original https://explosm.net/comics/planting-seeds
New Cyanide and Happiness Comic
Post Syndicated from daroc original https://lwn.net/Articles/986997/
Security updates have been issued by Fedora (community-mysql, iaito, and radare2), Oracle (python3.12-setuptools and tomcat), Red Hat (krb5 and podman), Slackware (ffmpeg), SUSE (apache2, expat, firefox, webkit2gtk3, and xen), and Ubuntu (imagemagick and libxstream-java).
Post Syndicated from LGR original https://www.youtube.com/watch?v=wNS6eCPlF8o
Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/08/23/key-takeaways-from-the-take-command-summit-navigating-new-sec-cybersecurity-disclosure-rules/
Understanding and complying with the new SEC Cybersecurity Disclosure Rules is a daunting task for many organizations. The Rapid7 Take Command Summit provided an in-depth look at these regulations, offering valuable guidance for cybersecurity professionals.
Here are three key takeaways from the session that are crucial for ensuring compliance and enhancing your organization’s cybersecurity posture.
1. Understand Materiality and Disclosure Requirements
One of the most critical aspects of the new SEC rules is determining the materiality of a cybersecurity incident. Kyra Ayo Caros, Director, Corporate Securities & Compliance at Rapid7 said, “materiality in this context is what would be material for investors to know…what sort of incident would your stakeholders or stockholders need to know about?” This involves assessing the incident’s impact on business operations and financial results. Companies must disclose material incidents within four days of determining their significance, highlighting the need for a robust incident response and evaluation process.
2. Foster Cross-Departmental Collaboration
Effective compliance with SEC rules requires coordination across various departments. Legal Counsel, Cybersecurity Services Group, Venable LLP Harley Geiger emphasized the importance of involving security, legal, and communications teams early in the process to meet disclosure requirements effectively. “Companies should ensure that security, legal, and communications teams are part of the process early on to collaborate on the most effective way of meeting these disclosure requirements.” This collaboration ensures that all relevant information is accurately assessed and reported.
3. Build a Comprehensive Cybersecurity Risk Management Program
The SEC rules also mandate annual disclosure of cybersecurity risk management processes and the role of senior management in overseeing these efforts. Organizations need to describe how they integrate cybersecurity into their overall risk management and governance framework. “It’s crucial to provide an accurate snapshot of your cybersecurity processes and management’s oversight to ensure investor trust,” said Ayo Caros. Ensuring these disclosures are accurate and reflect actual practices is vital for maintaining transparency and compliance.
57% of our post event survey respondents found the complexity and scope of regulations to be the most inhibiting factor in abiding by the SEC Cybersecurity Disclosure Rules. Navigating these intricate requirements poses a significant challenge, often leading to compliance difficulties.
The SEC Cybersecurity Disclosure Rules require a strategic and collaborative approach to ensure compliance and transparency. Understanding materiality, fostering cross-departmental collaboration, and building a comprehensive cybersecurity risk management program are essential steps. For a deeper dive into these strategies and expert insights, click here to watch the full video from the Rapid7 Take Command Event.
Post Syndicated from Fahim Sajjad original https://aws.amazon.com/blogs/devops/best-practices-for-working-with-pull-requests-in-amazon-codecatalyst/
According to the Well-Architected DevOps Guidance, “A peer review process for code changes is a strategy for ensuring code quality and shared responsibility. To support separation of duties in a DevOps environment, every change should be reviewed and approved by at least one other person before merging.” Development teams often implement the peer review process in their Software Development Lifecycle (SDLC) by leveraging Pull Requests (PRs). Amazon CodeCatalyst has recently released three new features to facilitate a robust peer review process. Pull Request Approval Rules enforce a minimum number of approvals to ensure multiple peers review a proposed change prior to a progressive deployment. Amazon Q pull request summaries can automatically summarize code changes in a PR, saving time for both the creator and reviewer. Lastly, Nested Comments allows teams to organize conversations and feedback left on a PR to ensure efficient resolution.
This blog will demonstrate how a DevOps lead can leverage new features available in CodeCatalyst to accomplish the following requirements covering best practices: 1. Require at least two people to review every PR prior to deployment, and 2. Reduce the review time to merge (RTTM).
If you are using CodeCatalyst for the first time, you’ll need the following to follow along with the steps outlined in the blog post:
Approval rules can be configured for branches in a repository. When you create a PR whose destination branch has an approval rule configured for it, the requirements for the rule must be met before the PR can be merged.
In this section, you will implement approval rules on the default branch (main in this case) in the application’s repository to implement the new ask from leadership requiring that at least two people review every PR before deployment.
Step 1: Creating the application
Pull Request approval rules work with every project but in this blog, we’ll leverage the Modern three-tier web application blueprint for simplicity to implement PR approval rules for merging to the main branch.
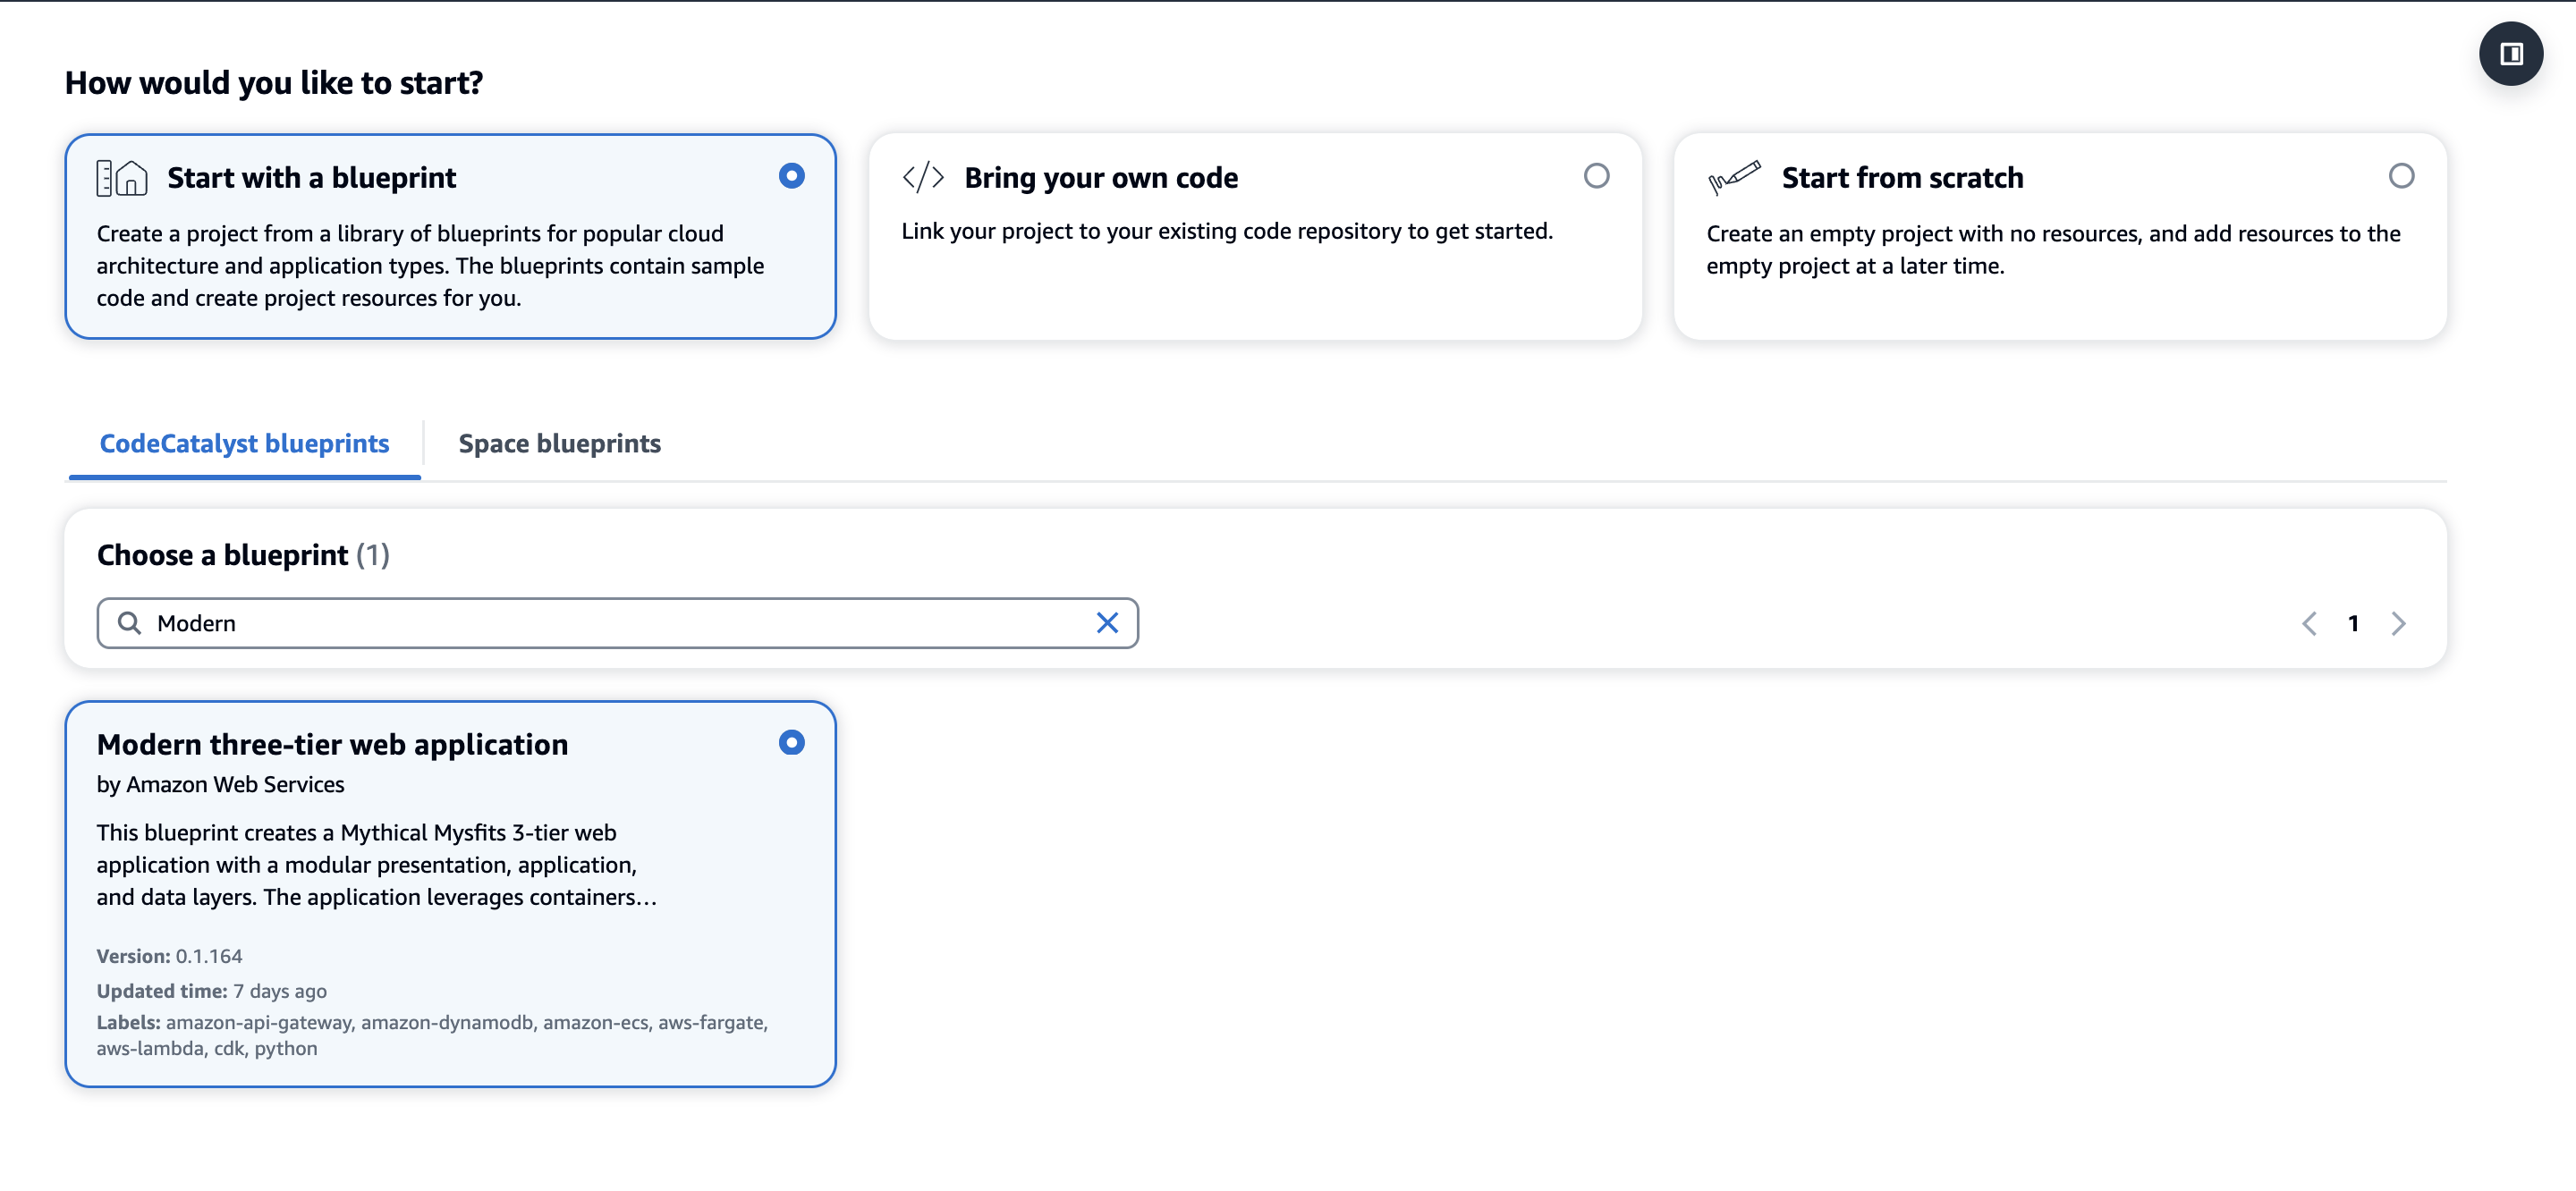
Figure 1: Creating a new Modern three-tier application Blueprint
Once the project is successfully created, the application will deploy via a CodeCatalyst workflow, assuming the AWS account and IAM role were setup correctly. The deployed application will be similar to the Mythical Mysfits website.
Step 2: Creating an approval rule
Next, to satisfy the new requirement of ensuring at least two people review every PR before deployment, you will create the approval rule for members when they create a pull request to merge into the main branch.
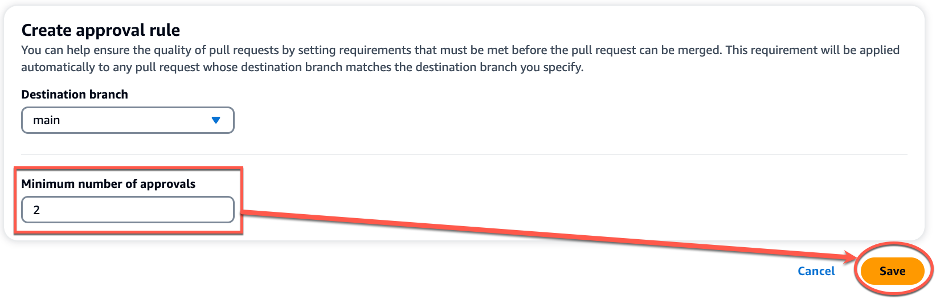
Figure 2: Creating a new approval rule
Note: You must have the Project administrator role to create and manage approval rules in CodeCatalyst projects. You cannot create approval rules for linked repositories.
When implementing approval rules and branch restrictions in your repositories, ensure you take into consideration the following best practices:
In this section, you walked through the steps to create a new approval rule to satisfy the requirement of ensuring at least two people review every PR before deployment on your CodeCatalyst repository.
Now, you begin exploring ways that can help development teams reduce MTTR. You begin reading about Amazon Q pull request summaries and how this feature can automatically summarize code changes and start to explore this feature in further detail.
While creating a pull request, in Pull request description, you can leverage the Write description for me feature, as seen in Figure 5 below, to have Amazon Q create a description of the changes contained in the pull request.
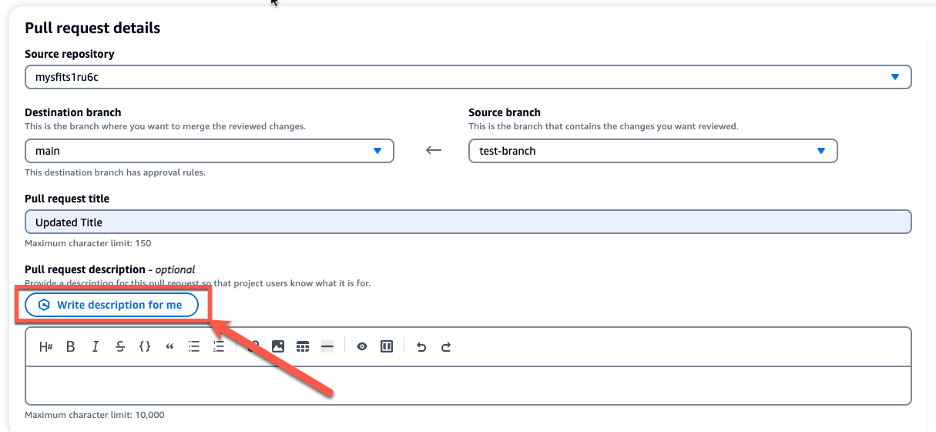
Figure 3: Amazon Q write description for me feature
Once the description is generated, you can Accept and add to description, as seen in Figure 6 below. As a best practice, once Amazon Q has generated the initial PR summary, you should incorporate any specific organizational or team requirements into the summary before creating the PR. This allows developers to save time and reduce MTTR in generating the PR summary while ensuring all requirements are met.
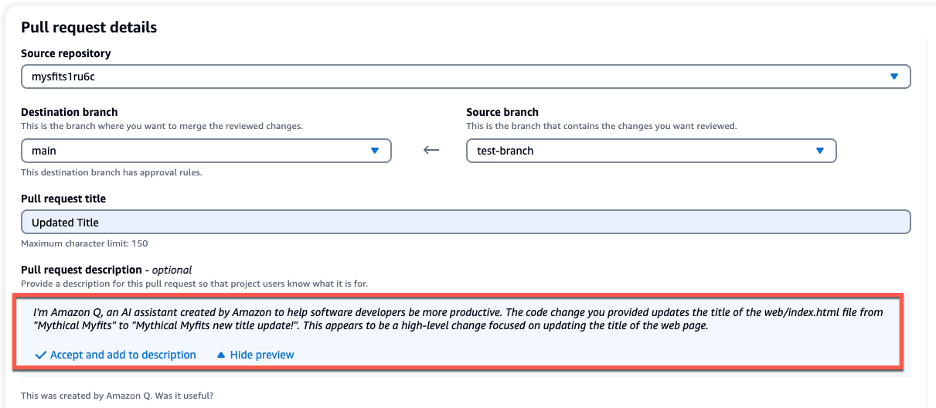
Figure 4: PR Summary generated by Amazon Q
CodeCatalyst offers an Amazon Q feature that summarizes pull request comments, enabling developers to quickly grasp key points. When many comments are left by reviewers, it can be difficult to understand common themes in the feedback, or even be sure that you’ve addressed all the comments in all revisions. You can use the Create comment summary feature to have Amazon Q analyze the comments and provide a summary for you, as seen in Figure 5 below.
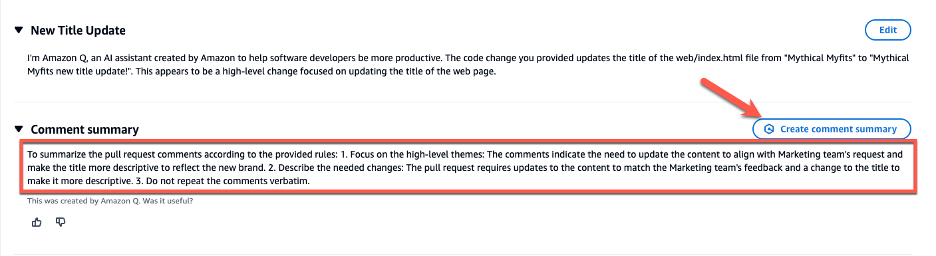
Figure 5: Comment summary
When reviewing various PRs for the development teams, you notice that feedback and subsequent conversations often happen within disparate and separate comments. This makes reviewing, understanding and addressing the feedback cumbersome and time consuming for the individual developers. Nested Comments in CodeCatalyst can organize conversations and reduce MTTR.
You’ll leverage the existing project to walkthrough how to use the Nested Comments feature:
Step 1: Creating the PR
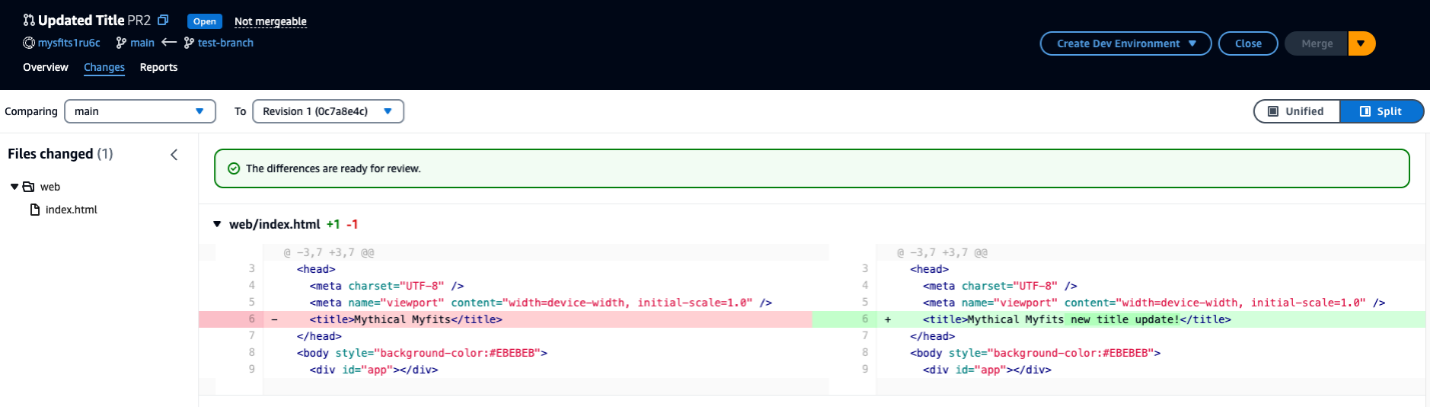
Figure 6: Pull Request with updated Title
Step 2: Review PR and add Comments
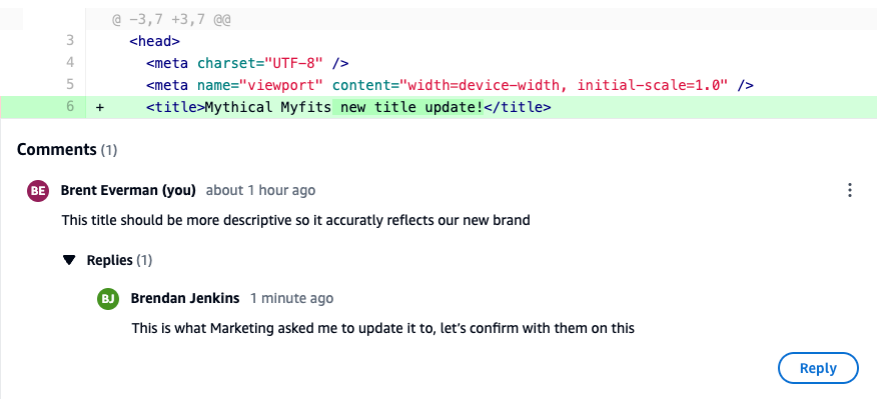
Figure 7: PR with Nested Comments
When leaving comments on PR in CodeCatalyst, ensure you take into consideration the following best practices :
As part of following the steps in this blog post, if you upgraded your space to Standard or Enterprise tier, please ensure you downgrade to the Free tier to avoid any unwanted additional charges. Additionally, delete any projects you may have created during this walkthrough.
In today’s fast-paced software development environment, maintaining a high standard for code changes is crucial. With its recently introduced features, including Pull Request Approval Rules, Amazon Q pull request summaries, and nested comments, CodeCatalyst empowers development teams to ensure a robust pull request review process is in place. These features streamline collaboration, automate documentation tasks, and facilitate organized discussions, enabling developers to focus on delivering high-quality code while maximizing productivity. By leveraging these powerful tools, teams can confidently merge code changes into production, knowing that they have undergone rigorous review and meet the necessary standards for reliability and performance.
Post Syndicated from Mangesh Budkule original https://aws.amazon.com/blogs/devops/accessing-amazon-q-developer-using-microsoft-entra-id-and-vs-code-to-accelerate-development/
In this blog post, I’ll explain how to use a Microsoft Entra ID and Visual Studio Code editor to access Amazon Q developer service and speed up your development. Additionally, I’ll explain how to minimize the time spent on repetitive tasks and quickly integrate users from external identity sources so they can immediately use and explore Amazon Web Services (AWS).Generative AI on AWS holds great ability for businesses seeking to unlock new opportunities and drive innovation. AWS offers a robust suite of tools and capabilities that can revolutionize software development, generate valuable insights, and deliver enhanced customer value. AWS is committed to simplifying generative AI for businesses through services like Amazon Q, Amazon Bedrock, Amazon SageMaker, Data foundation & AI infrastructure.
Amazon Q Developer is a generative AI-powered assistant that helps developers and IT professionals with all of their tasks across the software development lifecycle. Amazon Q Developer assists with coding, testing, and upgrading to troubleshooting, performing security scanning and fixes, optimizing AWS resources, and creating data engineering pipelines.
A common request from Amazon Q Developer customers is to allow developer sign-ins using established identity providers (IdP) such as Entra ID. Amazon Q Developer offers authentication support through AWS Builder ID or AWS IAM Identity Center. AWS Builder ID is a personal profile for builders. IAM Identity Center is ideal for an enterprise developer working with Amazon Q and employed by organizations with an AWS account. When using the Amazon Q Developer Pro tier, the developer should authenticate with the IAM Identity Center. See the documentation, Understanding tiers of service for Amazon Q Developer for more information.
The flow for accessing Amazon Q Developer through the IAM Identity Center involves the authentication of Entra ID users using Security Assertion Markup Language (SAML) 2.0 authentication (Figure 1).
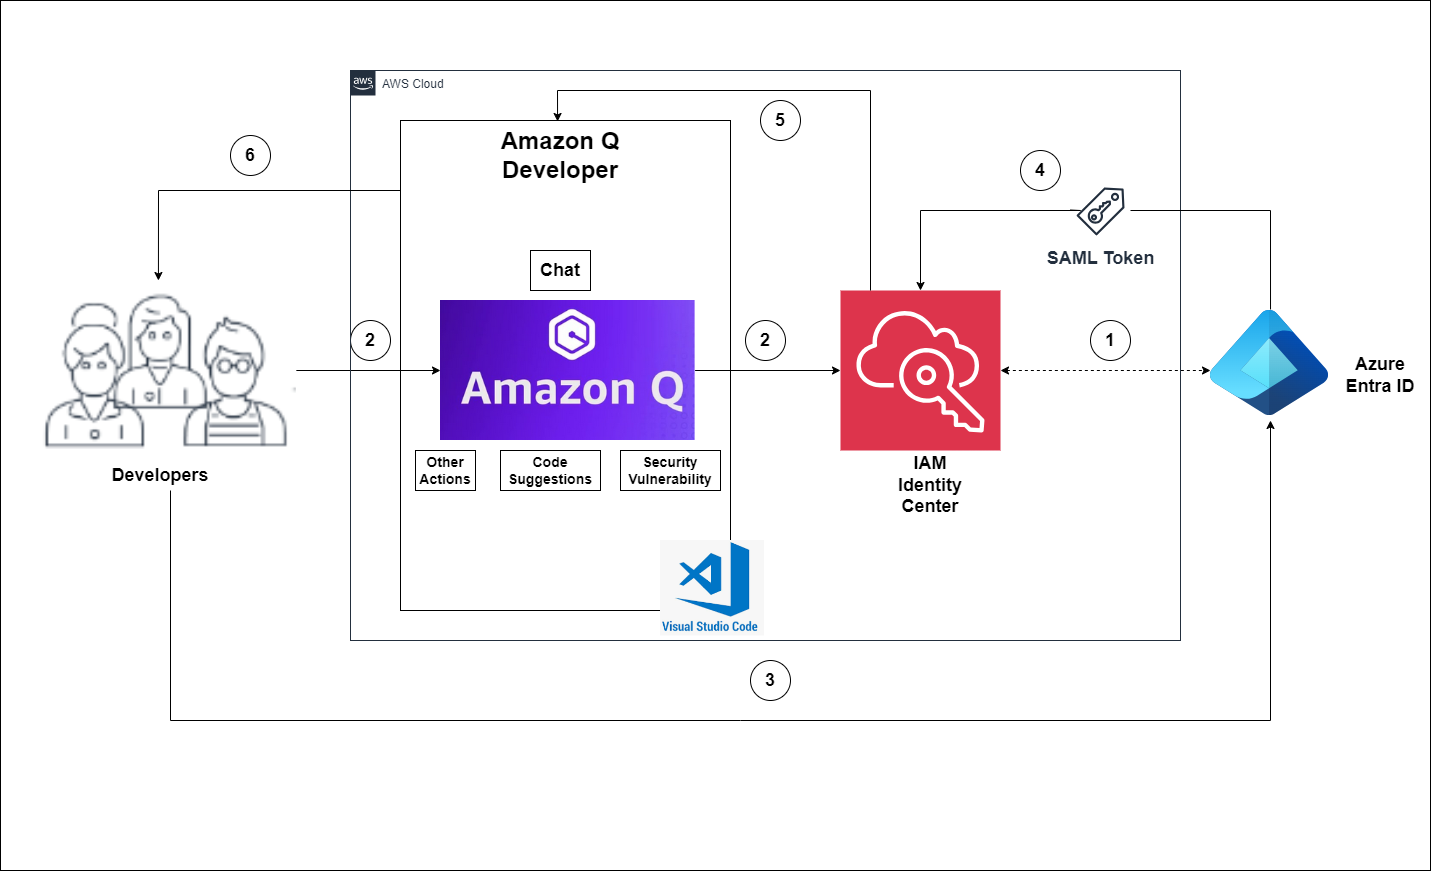
Figure 1 – Solution Overview
The flow for accessing Amazon Q Developer through the IAM Identity Center involves the authentication of Entra ID users using SAML 2.0 authentication. (Figure 1).
Prerequisites
In order to perform the following procedure, make sure the following are in place.
In this section, I will show how you can create a SAML base connection between Entra ID and AWS Identity Center so you can access AWS generative AI services using your Entra ID.
Note: You need to switch the console between Entra ID portal and AWS IAM Identity center. I recommend to open new browser tabs for each console.
Step 1 – Prepare your Microsoft tenant
Perform the below steps in the Entra identity provider section.
Now you have created AWS IAM Identity Center application, set up single sign-on to enable users to sign into their applications using their Entra ID credentials. Select the Single sign-on tab from the left navigation plane and select Setup single sign on.
Step 2 – Collect required service provider metadata from IAM Identity Center
In this step, you will launch the Change identity source wizard from within the IAM Identity Center console and retrieve the metadata file and the AWS specific sign-in URL. You will need this to enter when configuring the connection with Entra ID in the next step.
You need to enable this in order to configure SSO.

Figure 2 – Get started with AWS IAM Identity Center

Figure 3 – Select External identity provider

Figure 4 – Copy provider metadata URLs
Leave this page open, and move to the next step to configure the AWS IAM Identity Center enterprise application in Entra ID. Later, you will return to this page to complete the process.
Step 3 – Configure the AWS IAM Identity Center enterprise application in Entra ID
This procedure establishes one-half of the SAML connection on the Microsoft side using the values from the metadata file and Sign-On URL you obtained in the previous step.
Step 4 – Configure the Entra ID external IdP in AWS IAM Identity Center
Next you will return to the Change identity source wizard in the IAM Identity Center console to complete the second-half of the SAML connection in AWS.
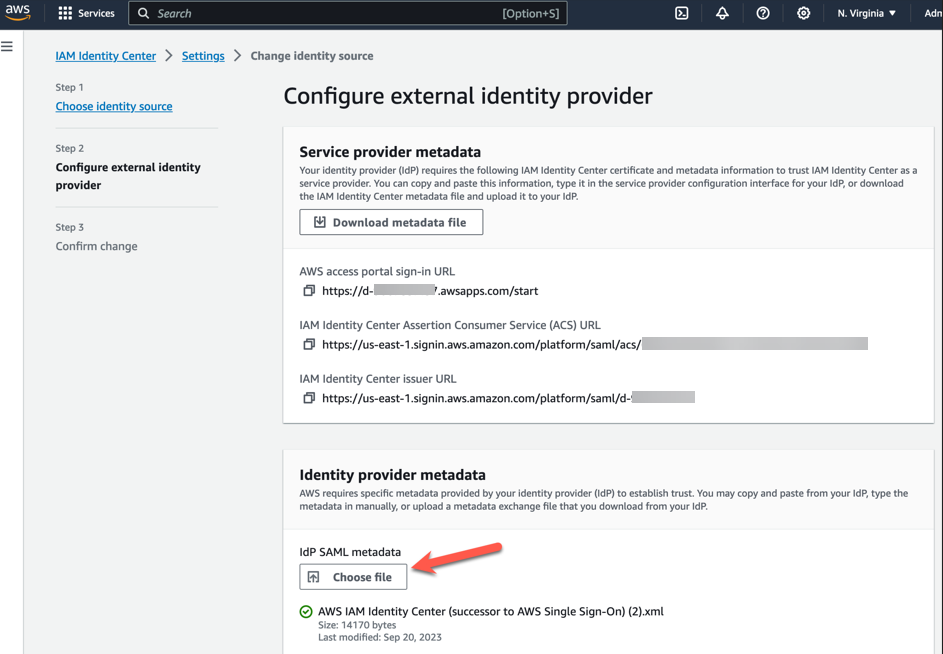
Figure 5 – AWS IAM Identity center metadata

Figure 6 – AWS IAM Identity center metadata

Figure 7 – AWS IAM Identity center metadata configuration changes progress console.
Step 5 – Configure and test your SCIM synchronization
In this step, you will set up automatic provisioning (synchronization) of user and group information from Microsoft Entra ID into IAM Identity Center using the SCIM v2.0 protocol. You configure this connection in Microsoft Entra ID using your SCIM endpoint for AWS IAM Identity Center and a bearer token that is created automatically by AWS IAM Identity Center.
To enable automatic provisioning of Entra ID users to IAM Identity Center, follow these steps using the IAM Identity Center application in Entra ID. For testing purposes, you can create a new user (TestUser) in Entra ID with details like First Name, Last Name, Email ID, Department, and more. Once you’ve configured SCIM synchronization, you can verify that this user and their relevant attributes were successfully synced to AWS IAM Identity Center.
In this procedure, you will use the IAM Identity Center console to enable automatic provisioning of users and groups coming from Entra ID into IAM Identity Center.
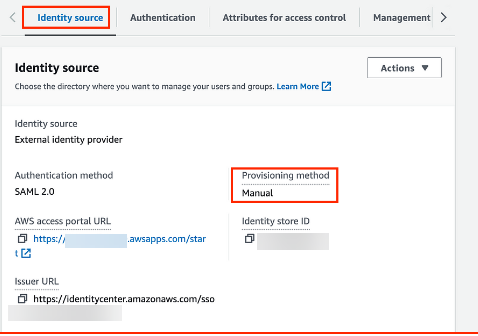
Figure 8 – AWS IAM Identity center console with provisioning method configuration details

Figure 9 – AWS IAM Identity center automatic provisioning info
Step 6 – Configure automatic provisioning in Entra ID
Now that you have your test user in place and have enabled SCIM in IAM Identity Center, you can proceed with configuring the SCIM synchronization settings in Entra ID.

Figure 10 – Azure Enterprise AWS IAM Identity center application provisioning configuration tab

Figure 11 – Azure Enterprise AWS IAM Identity center application provisioning testing status

Figure 12 – AWS IAM Identity center application Start provisioning tab
Note : The default provisioning interval is set to 40 minutes. Our users (Figure 13) are successfully provisioned and are now available in the AWS IAM Identity Center console.
In this section, you will verify that TestUser user was successfully provisioned and that all attributes are displayed in IAM Identity Center (Figure 13).
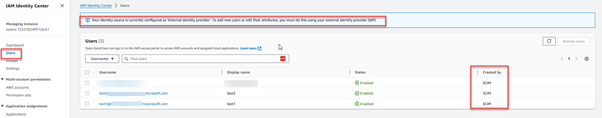
Figure 13 – AWS IAM Identity center application user console example
In the Identity source in IDC section, enable Identity-aware console sessions (Figure 14). This enables AWS IAM Identity Center user and session IDs to be included in users’ AWS console sessions when they sign in. For example, Amazon Q Developer Pro uses identity-aware console sessions to personalize the service experience.
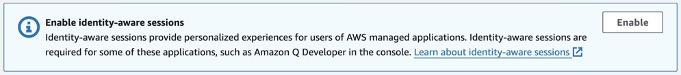
Figure 14 – Enable Identity aware console sessions
I have completed Entra ID and AWS Identity Center configuration. You can see Entra ID identity synced successfully with AWS IAM identity center.
Step 7 – Set up AWS Toolkit with IAM Identity Center
To use Amazon Q Developer, you will now set up the AWS Toolkit within integrated development environments (IDE) to establish authentication with the IAM Identity Center.
AWS Toolkit for Visual Studio Code is an open-source plug-in for VS Code that makes it easier for developers by providing an integrated experience to create, debug, and deploy applications on AWS. Getting started with Amazon Q Developer in VS Code is simple.
Step 8 – Setup Amazon Q Developer service with VS Code using AWS IAM identity center.
After installing the Amazon Q extension or plugin, authenticate through IAM Identity Center or AWS Builder ID.
After your identity has been subscribed to Amazon Q Developer Pro, complete the following steps to authenticate.
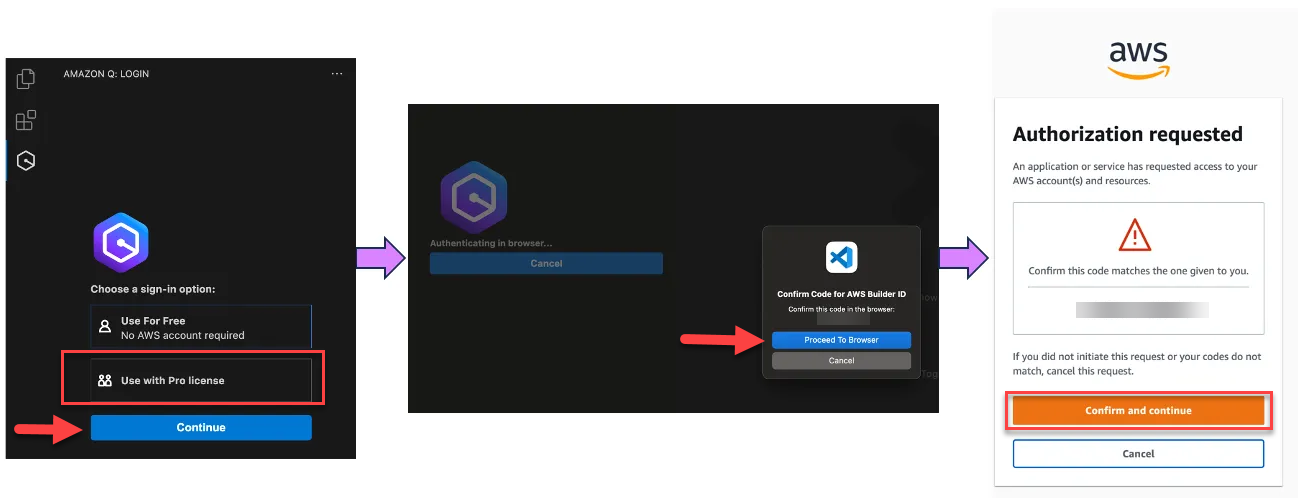
Figure 15 – Visual Studio code Amazon Q Developer extension

Figure 16 – Allow VS Code to access Amazon Q Developer
Step 9 – Test configuration examples
Now you have configured IAM identity Center access with VS code now you can chat, get inline code suggestions, check for security vulnerabilities with Amazon Q Developer to learn about, build, and operate AWS applications. I have mentioned a few examples of Amazon Q Suggestions, Code suggestions, Security Vulnerabilities during development for your reference (Figures 17 ,18 ,19 ,20).
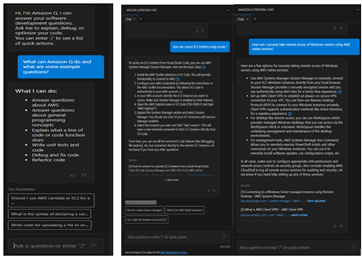
Figure 17 – Amazon Q suggestion examples
Example of developers get the recommendations using Amazon Q developer.
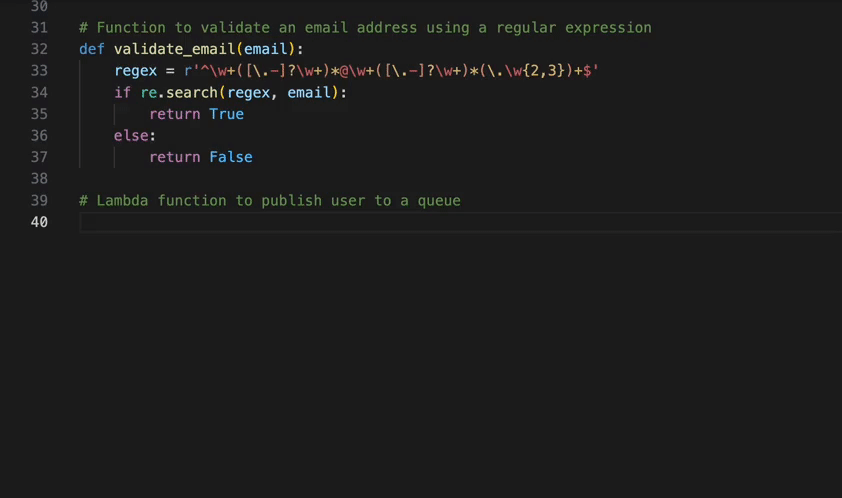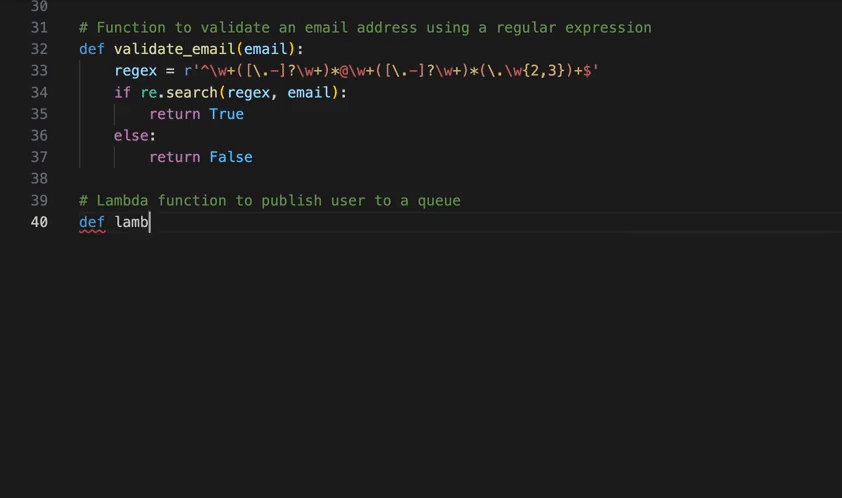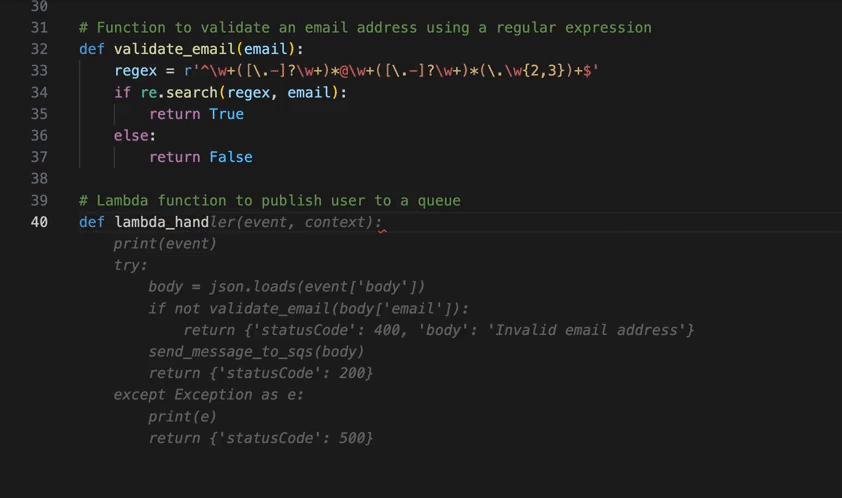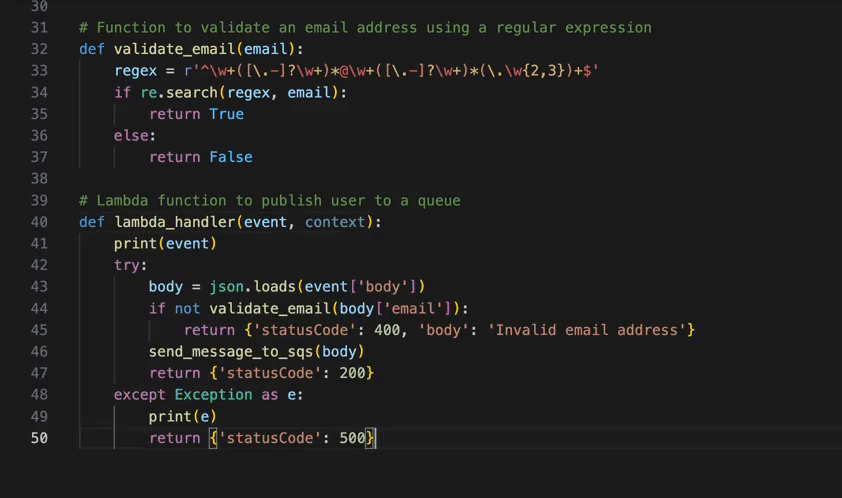
Figure 18 – Amazon Q Developer example
Figure 19 – Generate code, explain code, and get answers to questions about software development.
Example of integrating secure coding practices early in the software development lifecycle using Amazon Q developer.
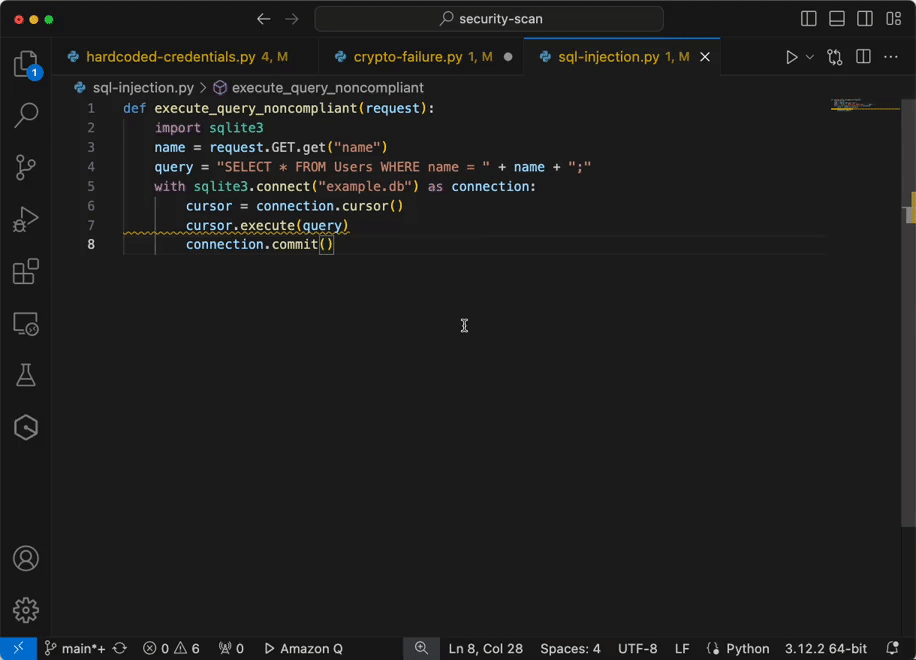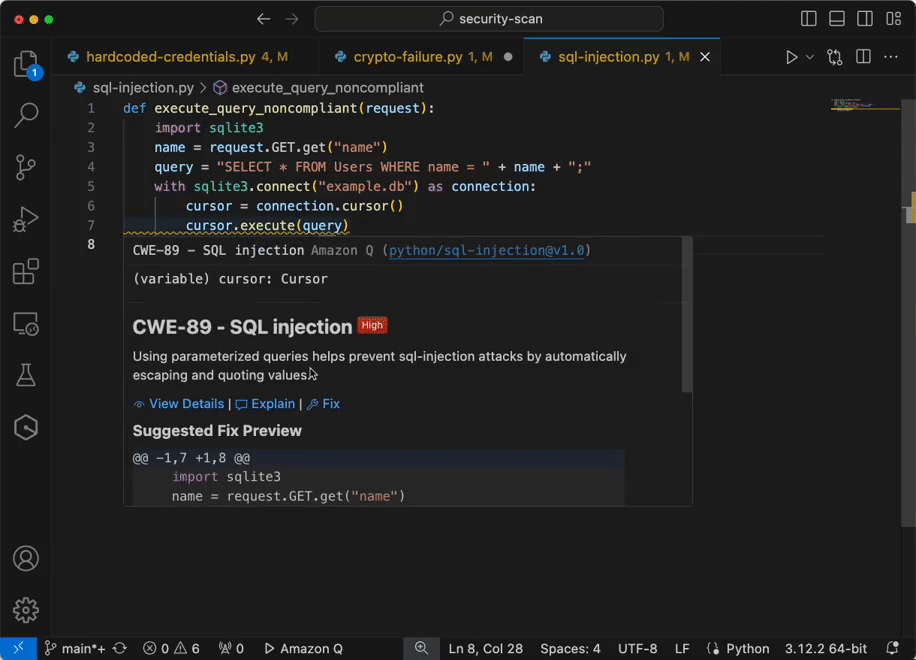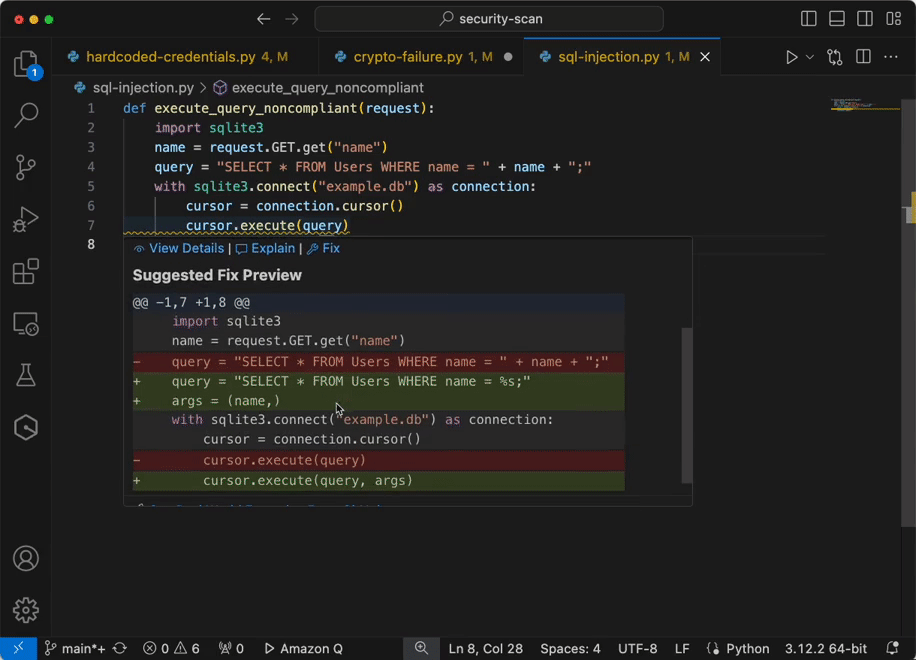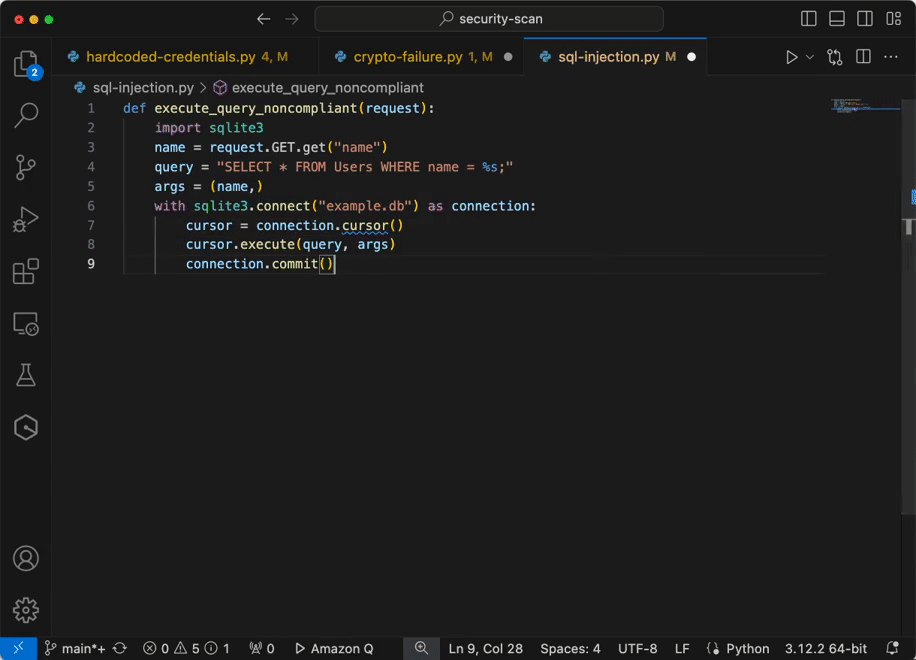
Figure 20 – Analyze and fix security vulnerabilities in your project example
Configuring AWS and Azure services from this blog will provision resources which incur cost. It is a best practice to delete configurations and resources that you are no longer using so that you do not incur unintended charges.
In this blog post, you learned how to integrate AWS IAM Identity Center and Entra ID IdP for accessing Amazon Q Developer service using VS Code IDE, which speeds up development. Next, you set up the AWS Toolkit to establish a secure connection to AWS using Entra ID credentials, granting you access to the Amazon Q Developer Professional Tier. Using SCIM automatic provisioning for user provisioning and access assignment saves time and speeds up onboarding, allowing for immediate use of AWS services using you own identity. Using Amazon Q, developers get the recommendations and information within their working environment in the IDE, enabling them to integrate secure coding practices early in the software development lifecycle. Developers can proactively scan their existing code using Amazon Q and remediate the security vulnerabilities found in the code.
To learn more about the AWS services
AWS Toolkit for Visual Studio Code
Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center
How to use Amazon CodeWhisperer using Okta as an external IdP
Post Syndicated from Sai Srinivas Somarouthu original https://aws.amazon.com/blogs/devops/how-a-b-testing-and-multi-model-hosting-accelerate-generative-ai-feature-development-in-amazon-q/
In the rapidly evolving landscape of Generative AI, the ability to deploy and iterate on features quickly and reliably is paramount. We, the Amazon Q Developer service team, relied on several offline and online testing methods, such as evaluating models on datasets, to gauge improvements. Once positive results are observed, features were rolled out to production, introducing a delay until the change affected 100% of customers.
This blog post delves into the impact of A/B testing and Multi-Model hosting on deploying Generative AI features. By leveraging these powerful techniques, our team has been able to significantly accelerate the pace of experimentation, iteration, and deployment. We have not only streamlined our development process but also gained valuable insights into model performance, user preferences, and the potential impact of new features. This data-driven approach has allowed us to make informed decisions, continuously refine our models, and provide a user experience that resonates with our customers
A/B testing is a controlled experiment, and a widely adopted practice in the tech industry. It involves simultaneously deploying multiple variants of a product or feature to distinct user segments. In the context of Amazon Q Developer, the service team leverages A/B testing to evaluate the impact of new model variants on the developer experience. This helps in gathering real-world feedback from a subset of users before rolling out changes to the entire user base.
To run an experiment, we take a random subset of developers and evenly split it into two groups: The control group continues to receive the base Amazon Q Developer experience, while the treatment group receives a different experience.
By carefully analyzing user interactions and telemetry metrics of the control group and comparing them to those from the treatment group, we can make informed decisions about which variant performs better, ultimately shaping the direction of future releases.
Whenever a user request is received, we perform consistent hashing on the user identity and assign the user to a cohort. Irrespective on which machine the algorithm runs, the user will be assigned the same cohort. This means that we can scale horizontally – user A’s request can be served by any machine and user A will always be assigned to group A from the beginning to the end of the experiment.
Individuals in the two groups are, on average, balanced on all dimensions that will be meaningful to the test. This means that we do not expose a cohort to have more than one experiment at any given time. This enables us to conduct multivariate experiments where one experiment does not impact the result of another.

The above diagram illustrates the process of user assignment to cohorts in a system conducting multiple parallel A/B experiments.
For some A/B experiments, we want to perform A/B experiments for users matching certain criteria. Assume we want to exclusively target Amazon Q Developer customers using the Visual Studio Code Integrated Development Environment (IDE). For such scenarios, we perform cohort allocation only for users who meet the criteria. In this example, we would divide a subset of Visual Studio Code IDE users into control and treatment cohorts.
Early on, we realized that we will need to host hundreds of models. To achieve this, we run multiple Amazon Elastic Container Service (Amazon ECS) clusters to host different models. We leverage Application Load Balancer’s path based routing to route traffic to the various models.

The above diagram depicts how Application Load Balancer redirects traffic to various models based on path-based routing. Where path1 is routing to control model and path2 is routing to treatment model 1 etc.
The IDE plugin polls the service endpoint asking if the developer belongs to the control or treatment group. Based on the response the user will be served the control or treatment experience.

The above diagram depicts how the IDE plugin provides different experience based on control or treatment group.
From the plugin, we publish telemetry metrics to our data plane. We honor opt-out settings of our users. If the user is opted-out, we do not store their data. In the data plane, we check the cohort of the caller. We publish telemetry metrics with cohort metadata to Amazon Data Firehose, which delivers the data to an Amazon OpenSearch Serverless destination.

The above diagram depicts how metrics are captured via the data plane into Amazon OpenSearch Serverless.
We publish the aggregated metrics to OpenSearch Serverless. We leverage OpenSearch Serverless to ingest and index various metrics to compare and contrast between control and treatment cohorts. We enable filtering based on metadata such as programming language and IDE.
Additionally, we publish data and metadata to a data lake to view, query and analyze the data securely using Jupyter Notebooks and dashboards. This enables our scientists and engineers to perform deeper analysis.
This post has focused on challenges Generative AI services face when it comes to fast experimentation cycles, the basics of A/B testing and the A/B testing capabilities built by the Amazon Q Developer service team to enable multi-variate service and client-side experimentation. We can gain valuable insights into the effectiveness of the new model variants on the developer experience within Amazon Q Developer. Through rigorous experimentation and data-driven decision-making, we can empower teams to iterate, innovate, and deliver optimal solutions that resonate with the developer community.
We hope you are as excited as us about the opportunities with Generative AI! Give Amazon Q Developer and Amazon Q Developer Customization a try today:
Amazon Q Developer Free Tier: https://aws.amazon.com/q/developer/#Getting_started/
Amazon Q Developer Customization: https://docs.aws.amazon.com/amazonq/latest/qdeveloper-ug/customizations.html
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=aYFWRRN1qOM
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/08/take-a-selfie-using-a-ny-surveillance-camera.html
This site will let you take a selfie with a New York City traffic surveillance camera.
EDITED TO ADD: BoingBoing post.
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/08/surveillance-watch.html
This is a fantastic project mapping the global surveillance industry.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=N0Jg42ipOr0