ArsTechnica is reporting on a “new” attack against RSA, one that bypasses factoring.
First, this attack isn’t new. The original research is from 2007. What is new is the implementation.
Second, it is a forgery attack. It allows an attacker to forge digital signatures. It does not recover the private key from the public key.
Third, the attack only works against pure signatures. That is, signatures without any formatting or padding. This is not generally how we use RSA in practice.
Fourth, speed is all relative. This is not a polynomial-time algorithm; it’s a subexponential-time algorithm. But it is somewhat faster than factoring. The authors were able to forge messages for 1024-bit RSA with 1380 CPU core-years (over five real-world months).
The authors have a webpage that explains the context much better than the article. And here’s the paper.
On September 27, 2026, Citrix disclosed eight new vulnerabilities affecting NetScaler ADC and NetScaler Gateway, including two critical remote code execution (RCE) vulnerabilities: CVE-2026-88771 and CVE-2026-88772. Both of these RCE vulnerabilities carry a critical CVSSv4 score of 9.5, and both have been confirmed as being actively exploited in the wild as zero-days prior to the vendor disclosure.
CVE-2026-88771 affects vulnerable NetScaler deployments in their default configuration, with no additional product features required. The vendor has also indicated that the attack complexity for exploiting CVE-2026-88771 is low, meaning reliable RCE is likely against all vulnerable NetScaler appliances regardless of their configuration. This is especially concerning due to the prevalence of NetScaler appliances.
CVE-2026-88772 is a memory corruption vulnerability and requires the DTLS feature to be enabled on the appliance. The vendor has indicated that the attack complexity is high, meaning achieving reliable exploitation may be more difficult for an attacker than that of CVE-2026-88771.
The U.S. Cybersecurity and Infrastructure Security Agency (CISA) reports active exploitation is occurring globally, and added both CVE-2026-88771 and CVE-2026-88772 to its Known Exploited Vulnerabilities (KEV) catalog on September 27, 2026. Multiple CERTs worldwide have begun issuingalerts due to the critical nature of this situation.
The following table summarizes all eight vulnerabilities:
The following vendor-supplied updates are available to remediate all eight vulnerabilities. Rapid7 strongly recommends updating affected NetScaler appliances on an emergency basis, outside of normal patching cycles, and investigating vulnerable appliances for signs of compromise.
Citrix NetScaler ADC and Citrix NetScaler Gateway 14.1-73.37 and later releases.
Citrix NetScaler ADC and Citrix NetScaler Gateway 13.1-64.23 and later releases of 13.1.
Citrix NetScaler ADC 14.1-FIPS 14.1-73.37 FIPS and later releases of 14.1-FIPS.
Citrix NetScaler ADC 13.1-FIPS and 13.1-NDcPP 13.1.37.279 and later releases of 13.1-FIPS and 13.1-NDcPP.
For the latest mitigation guidance, please refer to the vendor advisory.
Rapid7 customers
Exposure Command, InsightVM, and Nexpose
Exposure Command, InsightVM, and Nexpose customers can assess exposure to all the CVEs listed in this blog with authenticated vulnerability checks expected to be available in today’s (September 28) content release.
Intelligence Hub
Customers leveraging Rapid7’s Intelligence Hub can track the latest developments surrounding CVE-2026-88771 and CVE-2026-88772, including indicators of compromise (IOCs).
Alex, a teenaged learner, reads a homework assignment, ponders a little, and then opens an AI chatbot. A quick prompt produces a structured, well-written answer within seconds. Alex pastes the text into a document, tweaks a few words, and submits the work.
For many young people, this is becoming the norm.
Recent reports show that, in countries including the US and UK, over half of all teens use AI tools for homework, and 1 in 10 says they do most or all of their homework with chatbots. “I use it every day,” stated one 17-year-old student in a recent study (Pew Research, 2026), and went on to say how she relies on chatbots for everything from homework to life decisions. In another study, a teenager openly admitted to using AI to cheat on assignments, essays, and book reports (Harvard GSE, 2024).
This raises an important question: when AI technology does the work, what happens to the learning?
Researchers are increasingly concerned that such uncritical use of AI tools may lead to cognitive offloading, where learners outsource their thinking, and the weakening of higher-order thinking skills in young people, such as problem-solving, critical thinking and creativity.
To address these concerns, the Raspberry Pi Foundation and Google DeepMind have teamed up to create a new unit of research-informed lessons on large language models (LLMs) as part of Experience AI. Rather than focusing simply on how to use AI tools, the new unit helps learners understand how LLMs work, evaluate their outputs, and use them strategically to support their own learning.
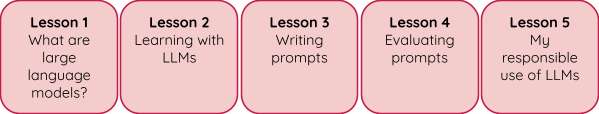
The unit, designed for 13- to 16-year-old learners, supports a learning-focused approach, drawing on metacognition, critical thinking, feedback literacy, and learning-centered prompt engineering. The five lessons in it support young people’s cognitive development, strengthen their metacognitive skills, and bolster their ability to strategically use LLMs for their learning. They draw on extensive research within Google DeepMind’s Learning team on how to scaffold around AI use to preserve ‘productive struggle’ and learner agency.
Research-informed pedagogies
Feedback literacy: Developing learners’ judgement of AI-generated outputs
The new ‘Large language models (LLMs): Using LLMs strategically for learning’ unit is grounded in learning science research, including feedback literacy. Feedback literacy refers to the skill of actively interpreting, judging and using information when learning, instead of passively receiving information.
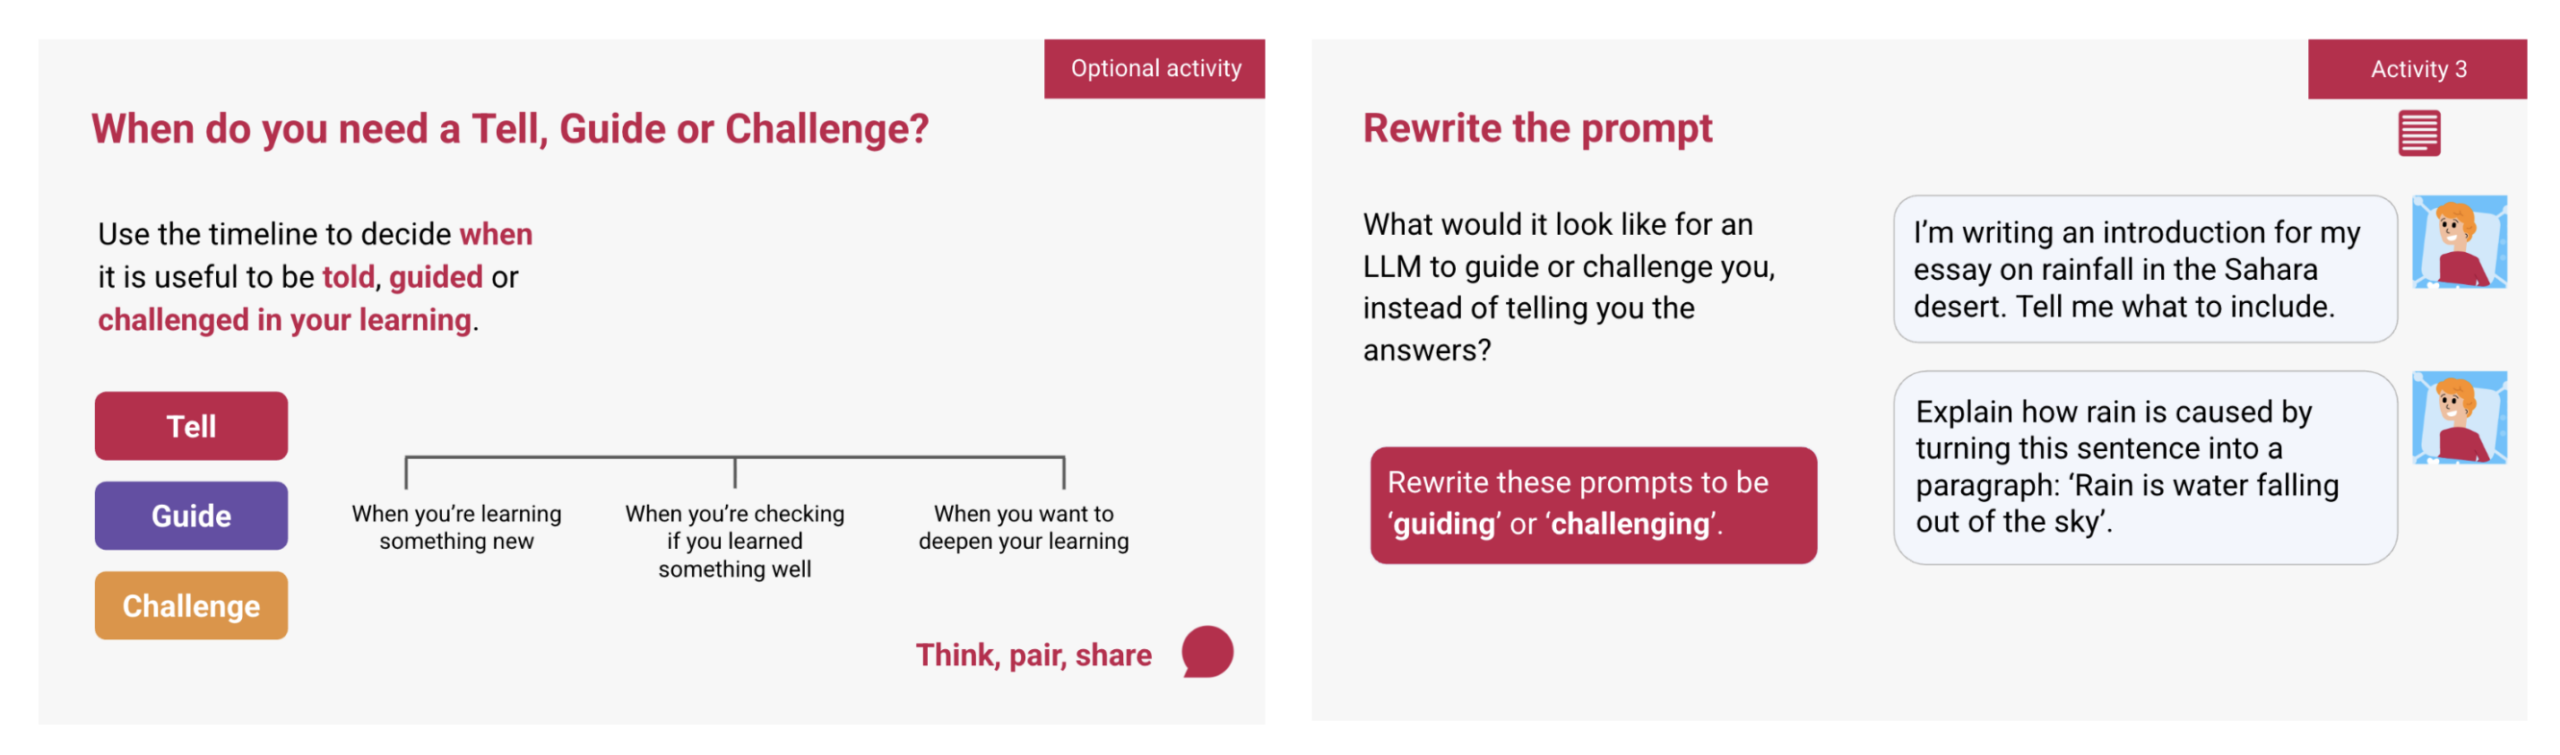
In the unit, learners explore three types of information, also called ‘feedback types’:
Telling: When someone is given the answer straight away
Guiding: When someone is guided with hints
Challenging: When someone is asked questions that make them think harder
Learners discover that deep learning requires a blend of all three feedback types. They also analyse LLM outputs and discover that LLMs default to providing the answer, usually in a ‘tell’ format.
To help learners strategically use LLMs for their learning, they are provided with prompting strategies that elicit LLM outputs in ‘guide’ and ‘challenge’ formats. This helps learners engage more deeply with their own learning and develop higher-order thinking skills.
Prompting techniques for learning, not just answers
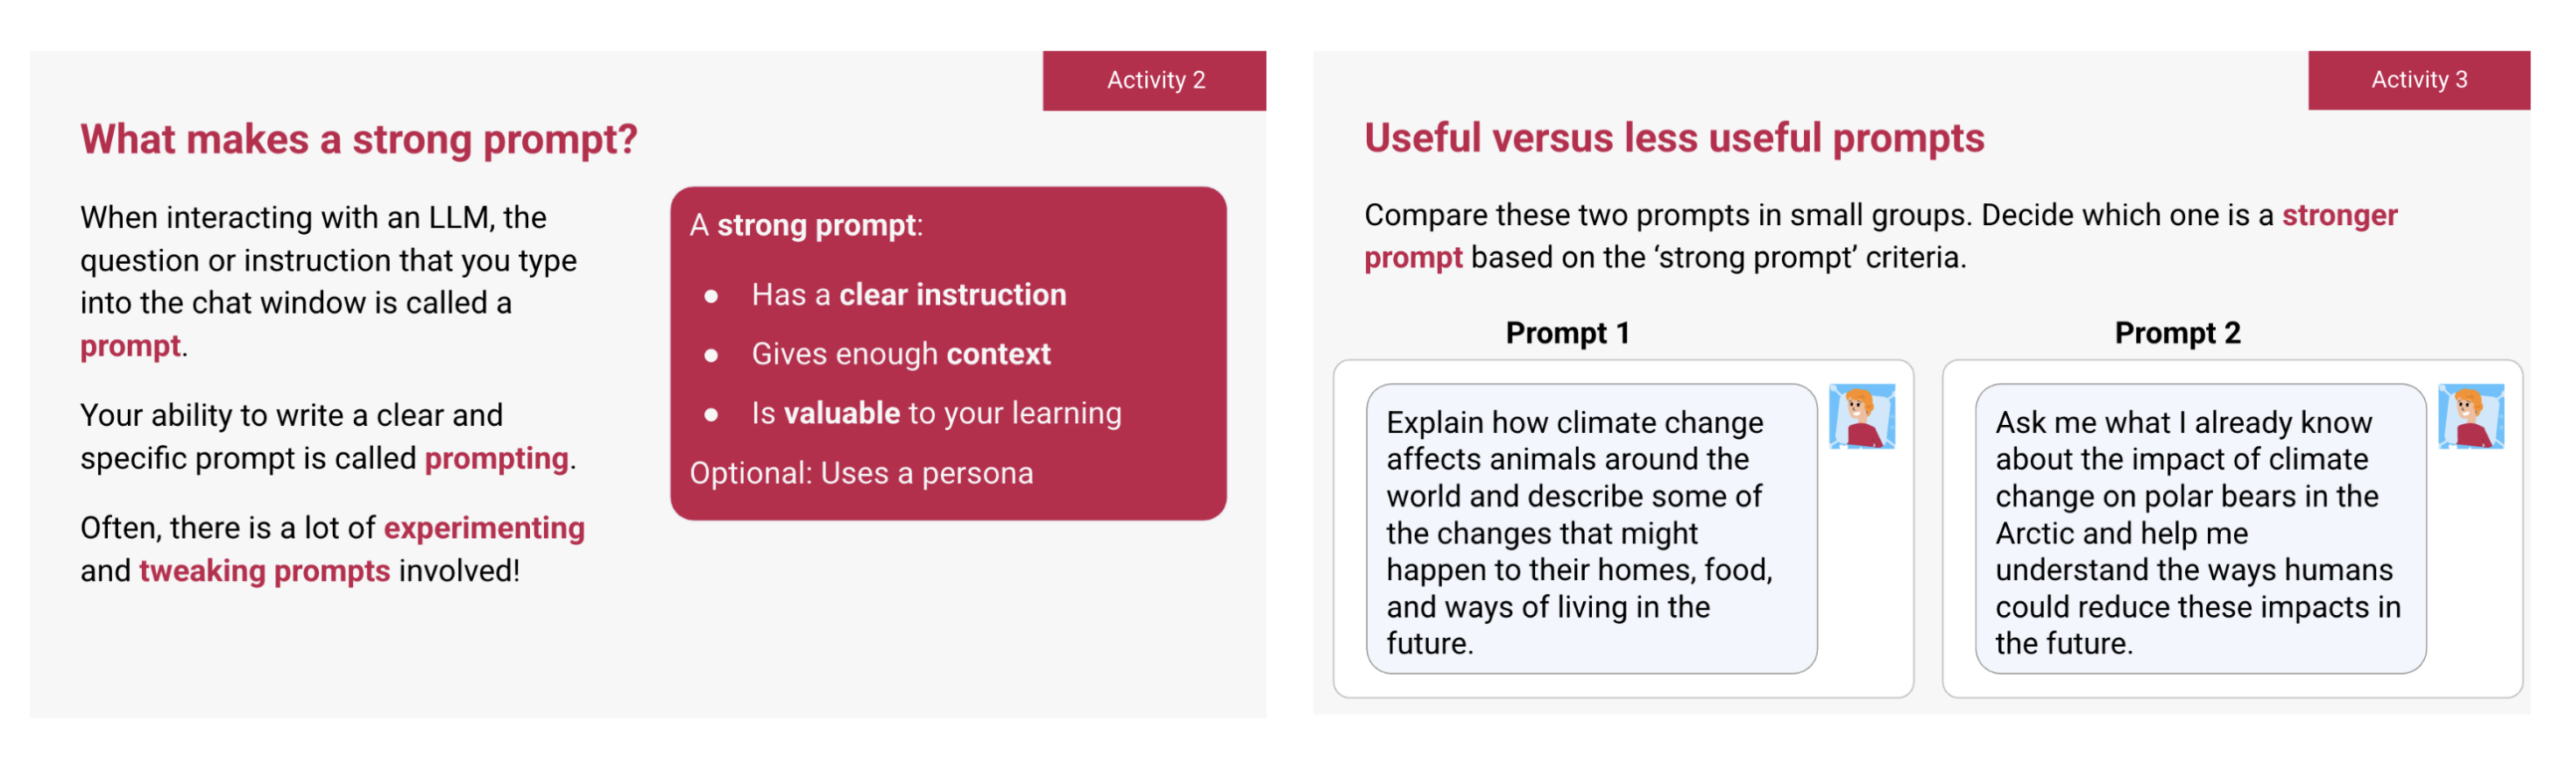
To help young people strategically use LLMs for their learning, the lessons include learning-centred, platform-agnostic prompting techniques. These include strategies borrowed from research papers on the most effective prompting frameworks. To make sure that the prompting strategies in the lessons remain effective over time and can be translated into different languages when we expand the resources, we did not use acronyms, unlike most popular prompting frameworks.
Building metacognition and future-ready skills
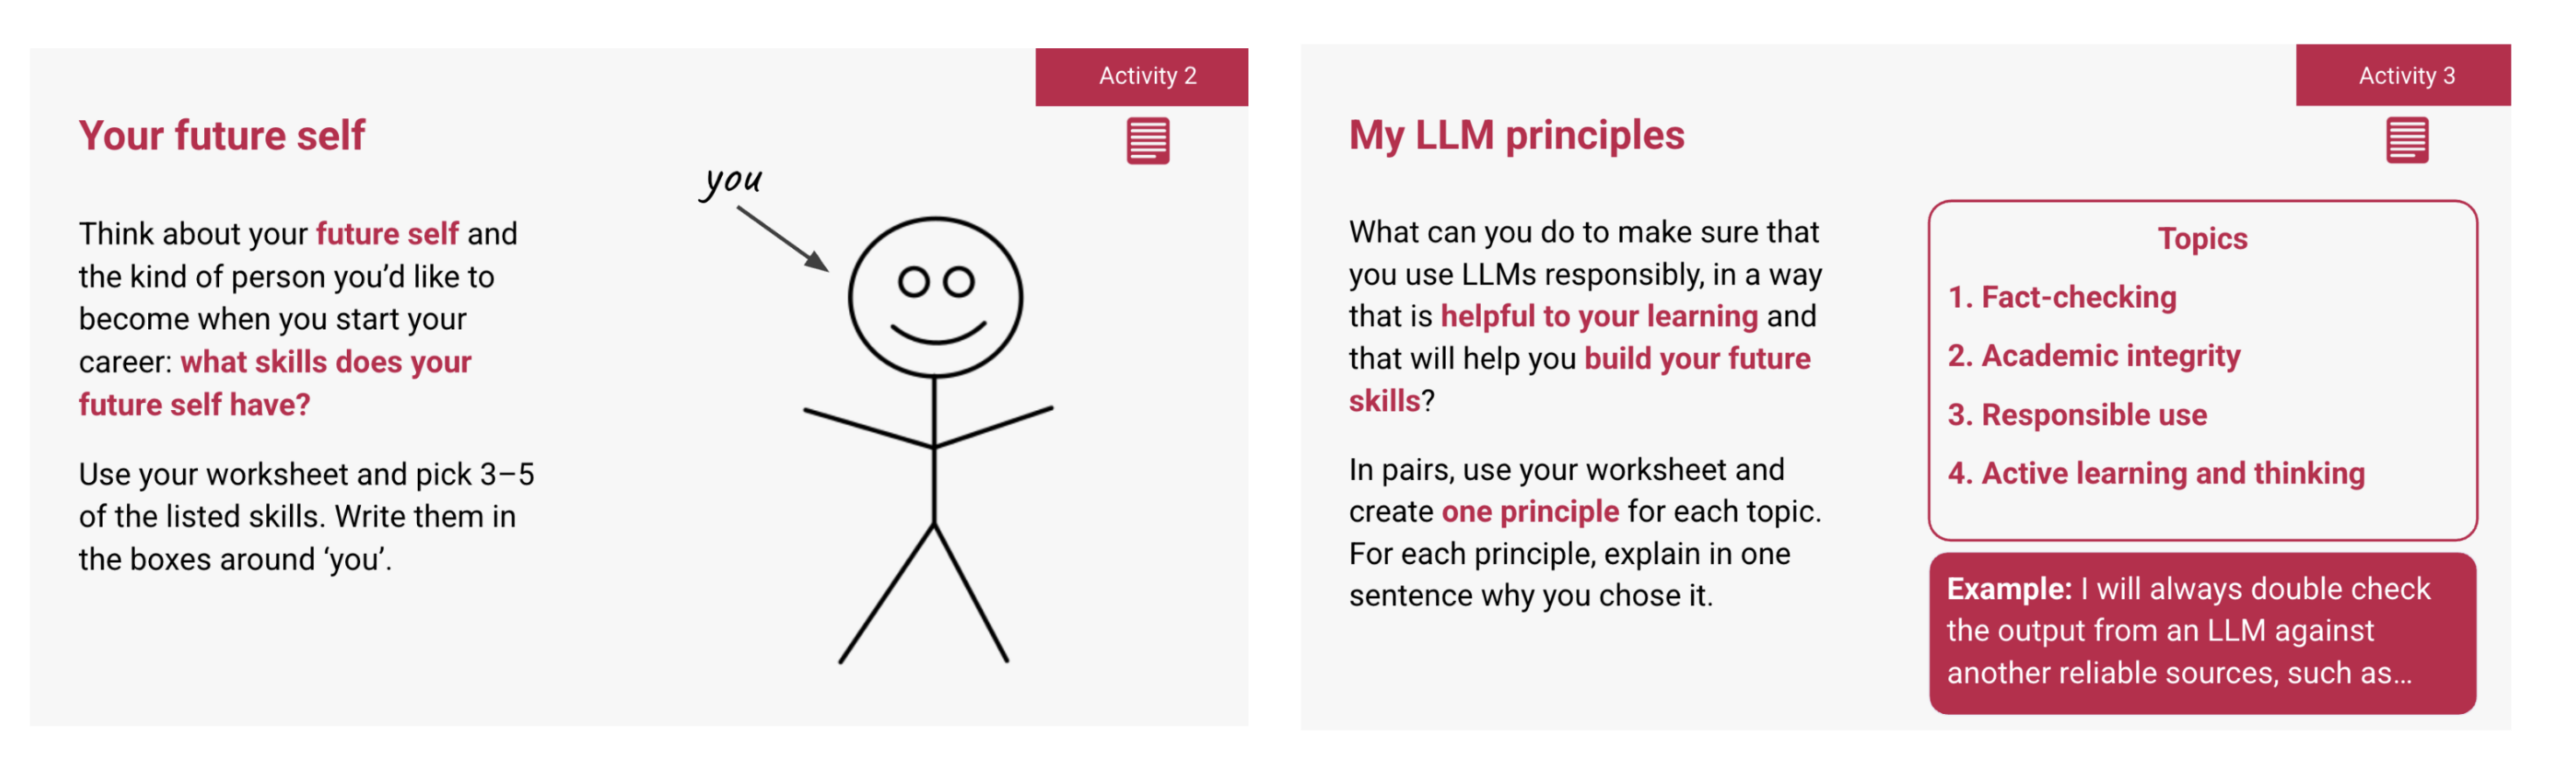
There are several industry reports highlighting the future-proof skills in the age of AI, such as problem solving, communication, critical thinking, collaboration and creativity skills. In the ‘Large language models’ unit, learners reflect on which skills they want to build and consider how their use of LLMs can support or hinder their development, helping them make responsible and intentional choices about using LLMs in ways that build their long-term capabilities rather than replace them.
There are also activities in the lesson resources that help learners understand the long-term impacts of cognitive offloading and uncritical LLM use on the development of their future skills. The resources encourage learners to stay actively engaged in their learning and be reflective of their LLM use when learning.
Uncovering LLM training data
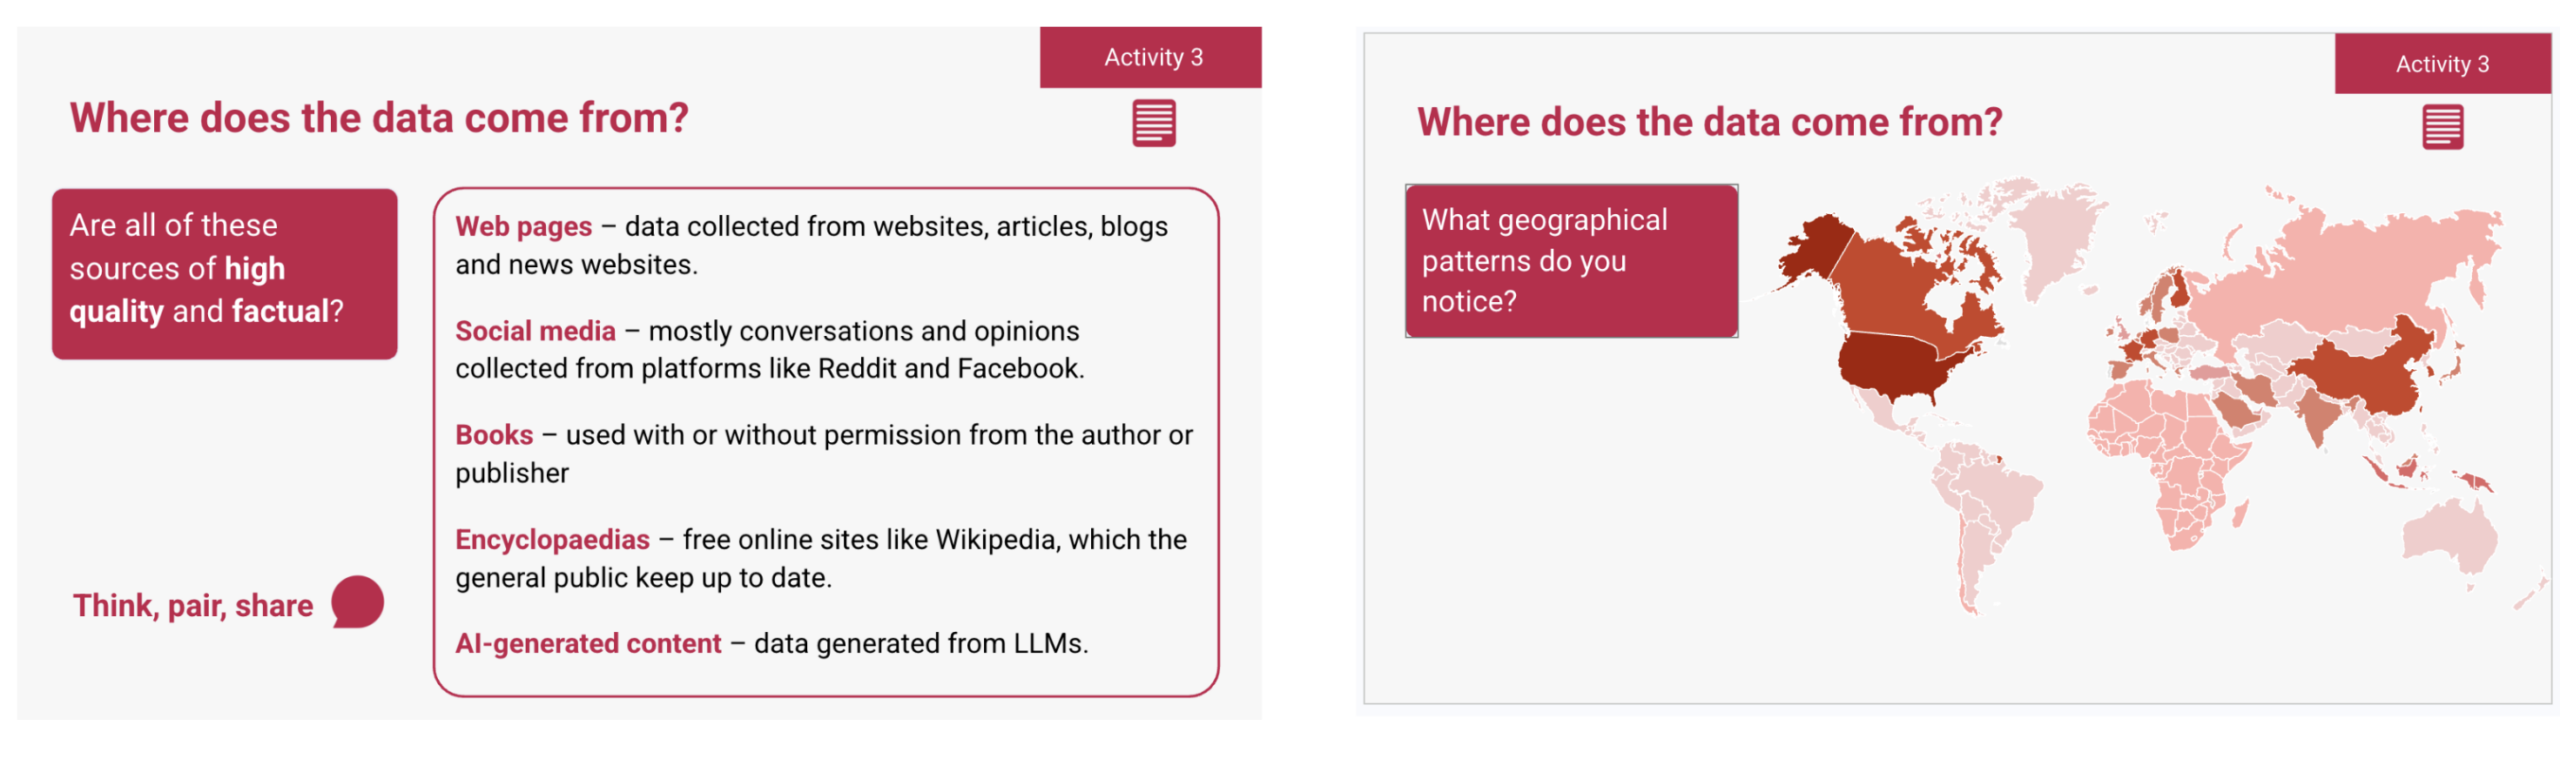
Many young people (Pew Research, 2026) use LLMs as search engines, believing that LLMs produce outputs that are always accurate. To address that misconception, the lessons include activities that question where the training data comes from, and how accurate those sources of data are.
For example, when young people discover that a portion of data that LLMs are trained on come from social media platforms like Reddit and Facebook, they are encouraged to question the quality and factuality of these sources through classroom-wide discussions. Through discussions and thinking exercises, learners are also encouraged to question whose voices, languages, cultures and perspectives are (and are not) represented in these AI models.
Looking ahead
As AI tools become more integrated in young people’s lives, many learners, like Alex, are tempted to turn to AI tools for quick answers, convenience, and support.
The ‘Large language models (LLMs): Using LLMs strategically for learning’ unit equips young people with the skills to use LLMs effectively, critically and strategically, in ways that are most helpful to their learning. Through research-informed lessons, they explore how LLMs are created, why their outputs are not always accurate and how to evaluate AI-generated responses.
Just as importantly, learners are encouraged to reflect on their own use of AI: when using an LLM supports their learning, when it does not, and how they can remain in control of their thinking, learning and skills development.
With these resources, young people like Alex are not discouraged from using LLMs, but encouraged to pause, rewrite their prompts in ways that are more helpful to their learning, evaluate the outputs they receive, and stay actively involved in their own thinking.
As we prepare young people for a future we do not yet know, the most important skill we can teach them is how to keep thinking. Who does the thinking, gets the learning.
We would like to thank all the educators across South Africa, Nigeria, Kenya, the United Kingdom, India and beyond who piloted these resources and shared their thoughtful feedback. Their contributions helped shape and strengthen the unit. We are also grateful to Google DeepMind for their continued support in the development of this unit.
The 7.3-rc5 kernel prepatch is out for
testing. Linus said: “I don’t think there’s any real pattern to it
other than ‘big’. But nothing looks particularly alarming, I think that
despite the diffstat it’s just the same old, same old.“
This week Cloudflare celebrates our 16th birthday. Like many 16-year-olds, we find ourselves looking around at the world we grew up in and feeling caught between the past and future. Also like many 16-year-olds, we look at all the change in the world and sometimes see risk. But, on balance, we come out incredibly optimistic for what lies ahead. What drives our optimism and fear is a recognition that change involves disruption.
The Internet is changing more today than at any point since Cloudflare launched back on September 27, 2010. Some of that change seems undoubtedly good. Some of it is upending the way we think the Internet works.
One significant change is the rate of growth of the web itself. From 2012 through 2025, the web plateaued and by some measures even shrank. That changed in mid-2025 when there was an explosion of new websites. The popular narrative is that growth has been driven by AI "slop." And, while there is some of that, that's not the majority of what we see.
Instead, AI has unleashed a new cohort of creators. Individuals with ideas but without coding skills who, aided by so-called "vibe coding" tools, are able to bring new creations to life. We're proud that the majority of these tools have Cloudflare's developer platform as their preferred deployment target. Technology at its best allows more people to express their creativity. We have front row seats to watch students around the world building apps to solve real-world problems. Startups with new business ideas getting built in record time. Today more than 7 million developers are building the future on Cloudflare’s developer platform.
The last year has also changed in terms of who — and increasingly what — is using the Internet. We originally forecast that automated traffic would pass human traffic in the second half of 2027. The rise of agents and AI crawlers pulled that date forward to May of 2026. And, if current trends continue — which, if anything, seems conservative — automated traffic will be 1,000 times human traffic in just five years. Not because we believe human traffic will decline, but because traffic from agents is exploding.
For people using them, these agents are already astonishing. Ask one to find you a flight, a contractor or a cheaper phone plan, and it will read more pages in a minute than you could in an afternoon, then come back with an answer. It does the legwork so you don't have to.
But that legwork isn’t free. If you ask your AI agent to suggest where you should go to lunch, it may survey 1,000 restaurant menus in the area only to suggest one. The one restaurant may get your business, but the other 999 had to shoulder the load of serving the agent without getting anything in return. The risk here is a tragedy of the commons problem where the users benefiting from the agents and their traffic don't bear the costs of the load they put on the system and therefore don't exercise appropriate restraint.
AI has made it easier than ever for those students and startups to build something. Agents could make it much harder for anyone to find it. Today, small businesses win customers with emotion or convenience. You patronize a certain deli because the person working the counter remembers your name or because it’s part of how you define your identity. Or you shop at a local store even though you know it doesn't have the best selection or prices but it's on your drive home.
Your agent doesn't care who remembers your name, and it isn't driving home past the local store. It goes with whatever it has the most information about, and that's usually whoever has been around the longest. The risk then is that as agents handle more and more commerce, they'll make it harder for new entrants to break in. That, in turn, is likely to lead to consolidation and a less robust business environment.
We were a new entrant once. Sixteen years ago this week, we launched Cloudflare on stage at TechCrunch Disrupt while our engineers sat in the audience fixing bugs. There were eight left when we walked on. By the time we walked off, they were fixed and we were live in five data centers on three continents. Nobody's agent would have recommended us. People took a chance on us anyway. We want the next new entrants to get the same chance.
That’s what we’re playing for. Not a future with five AI companies, but one with 500,000, spread around the world. Not one where content creators wither away and die because they can't be compensated, but one where anyone can create, reach a global audience and get paid for their work. And not one where a few mega corporations win by default, but one where new entrants with better products can serve customers well, and win.
Last year we wrote about what AI was doing to publishers. This year the same shift is reaching the restaurant and the deli. What replaces the Internet's old business model is the most interesting question of the next five years. This week, we take another swing at answering it.
Like every birthday, we're celebrating by giving presents instead of getting them, and some of the presents are for the 999 restaurants. Agents crawl the web the way search engines always have: everything, over and over, whether it's changed or not. Our data suggests more than half of what good bots fetch hasn't changed since their last visit. We've been working so that crawlers see more of the web while fetching only what's new, which cuts the load on the sites they crawl. And we're giving anyone who puts content or applications online a way to get paid when agents use what they've built.
Cloudflare's mission isn't to build a better Internet, it's to help build a better Internet. That means we can't do it alone. So this week we'll also be announcing partnerships with companies and organizations that want the same future we do.
Like other 16-year-olds in this new era of AI, we get to ship our opinions. We're shipping them for an Internet that still has room for a teenager launching their first app, the deli where they remember your name, and whoever is building the next Cloudflare.
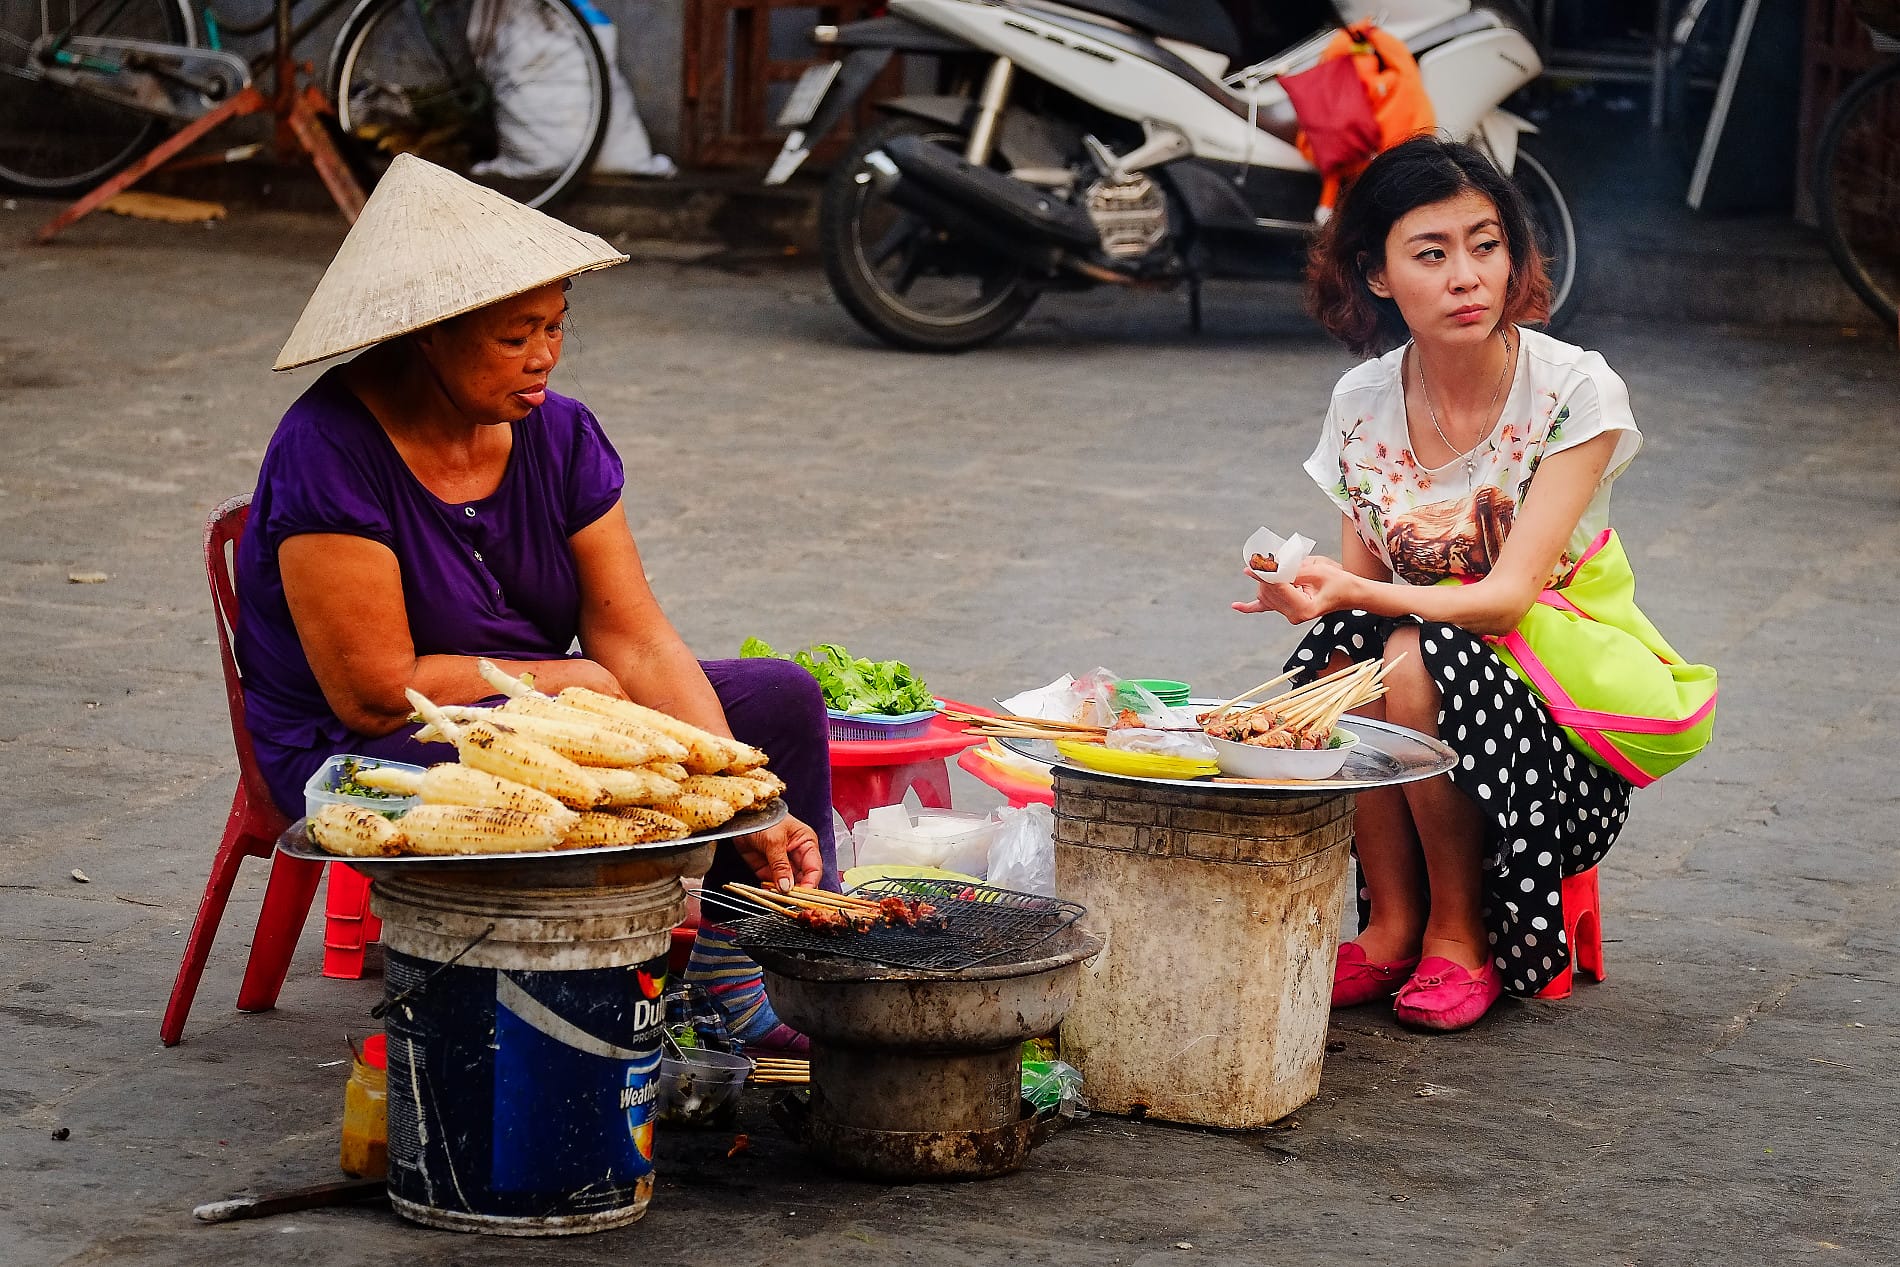
Големите градове, където и да се намират, вероятно са най-удачните места за улична фотография. Но Азия, без съмнение е раят за уличните фотографи – с многото хора, свикнали да не разчитат на някаква дистанция или лично пространство; с цветовете; с динамиката, която е част от живота на улицата.
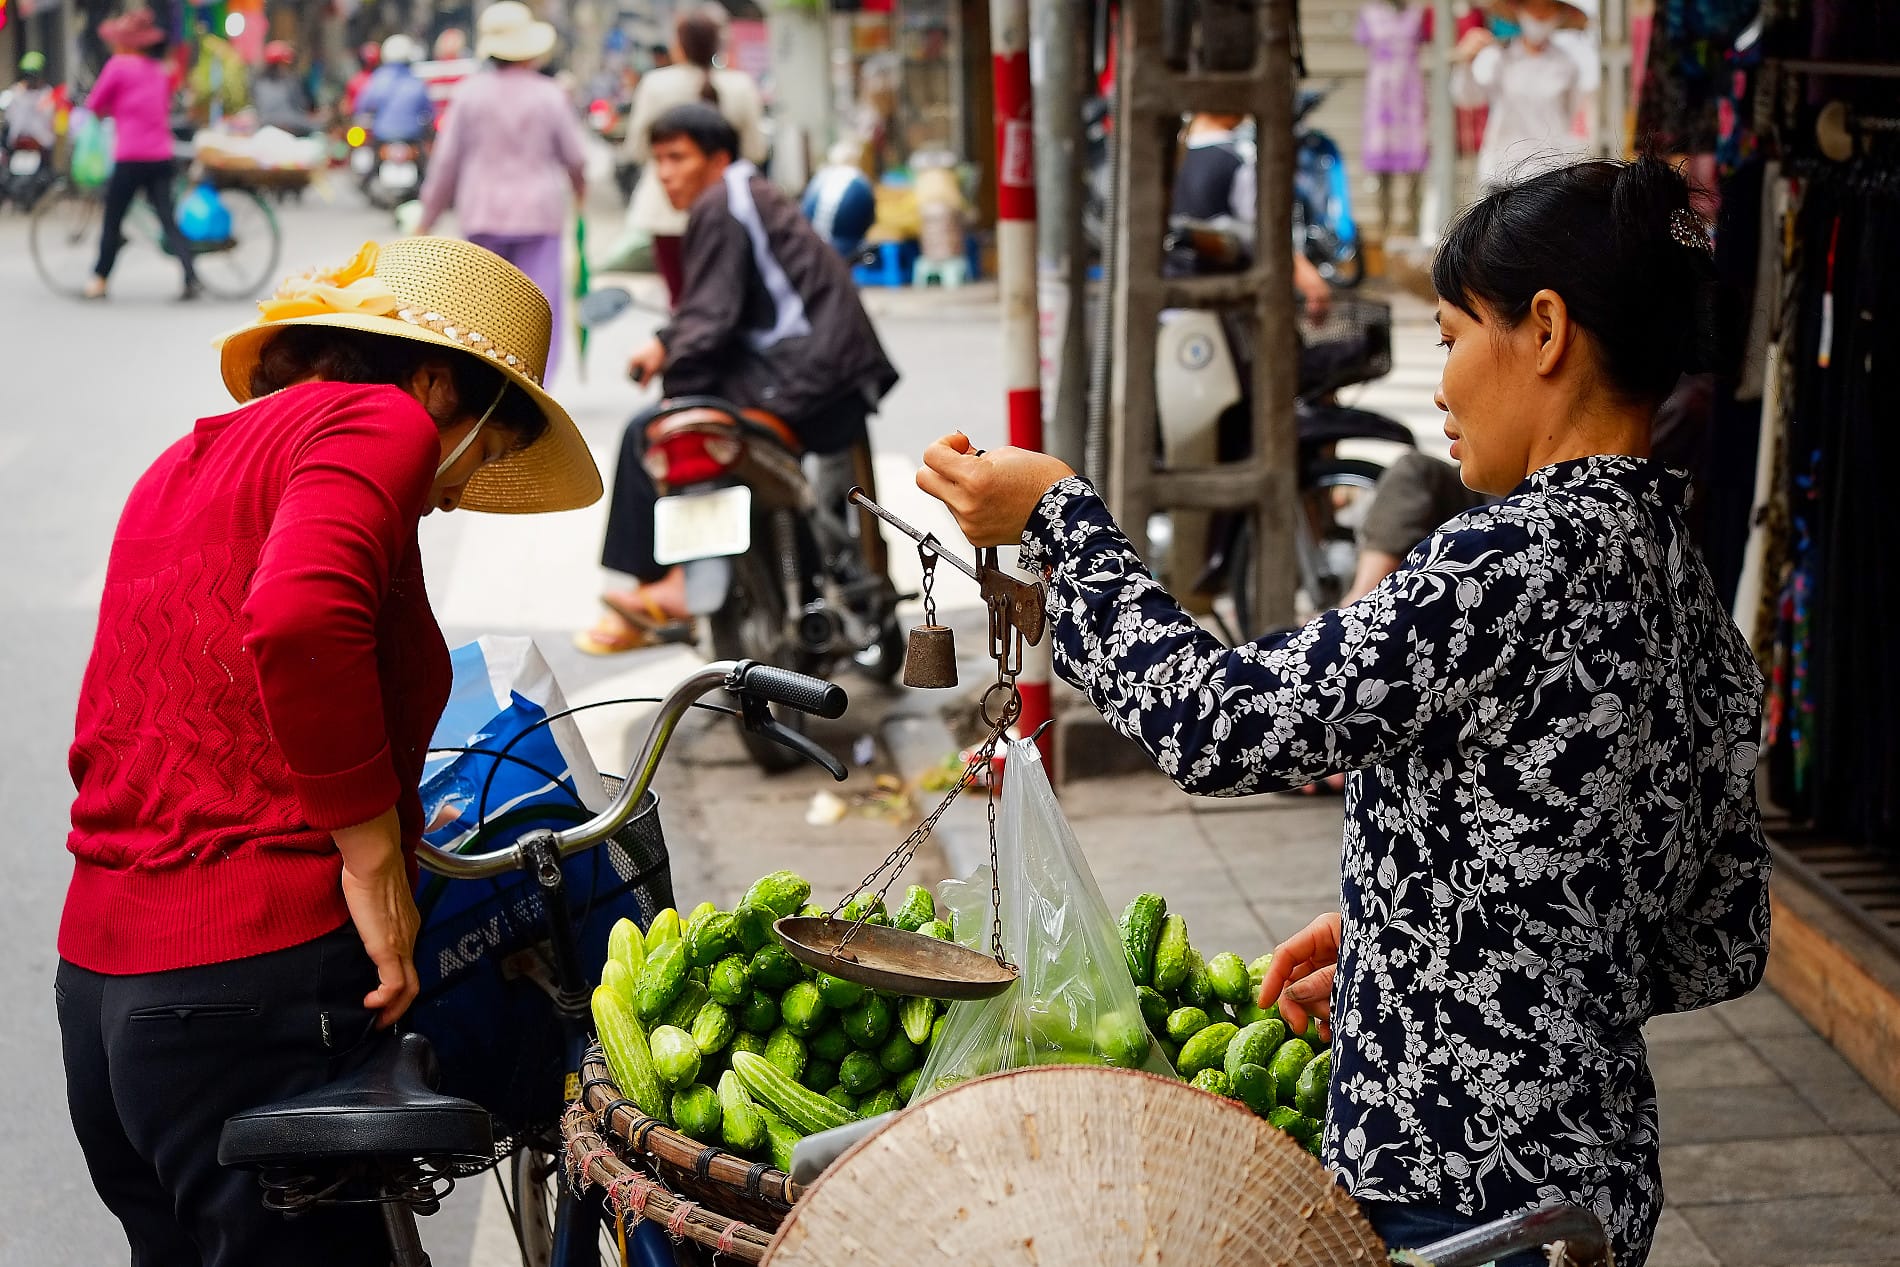
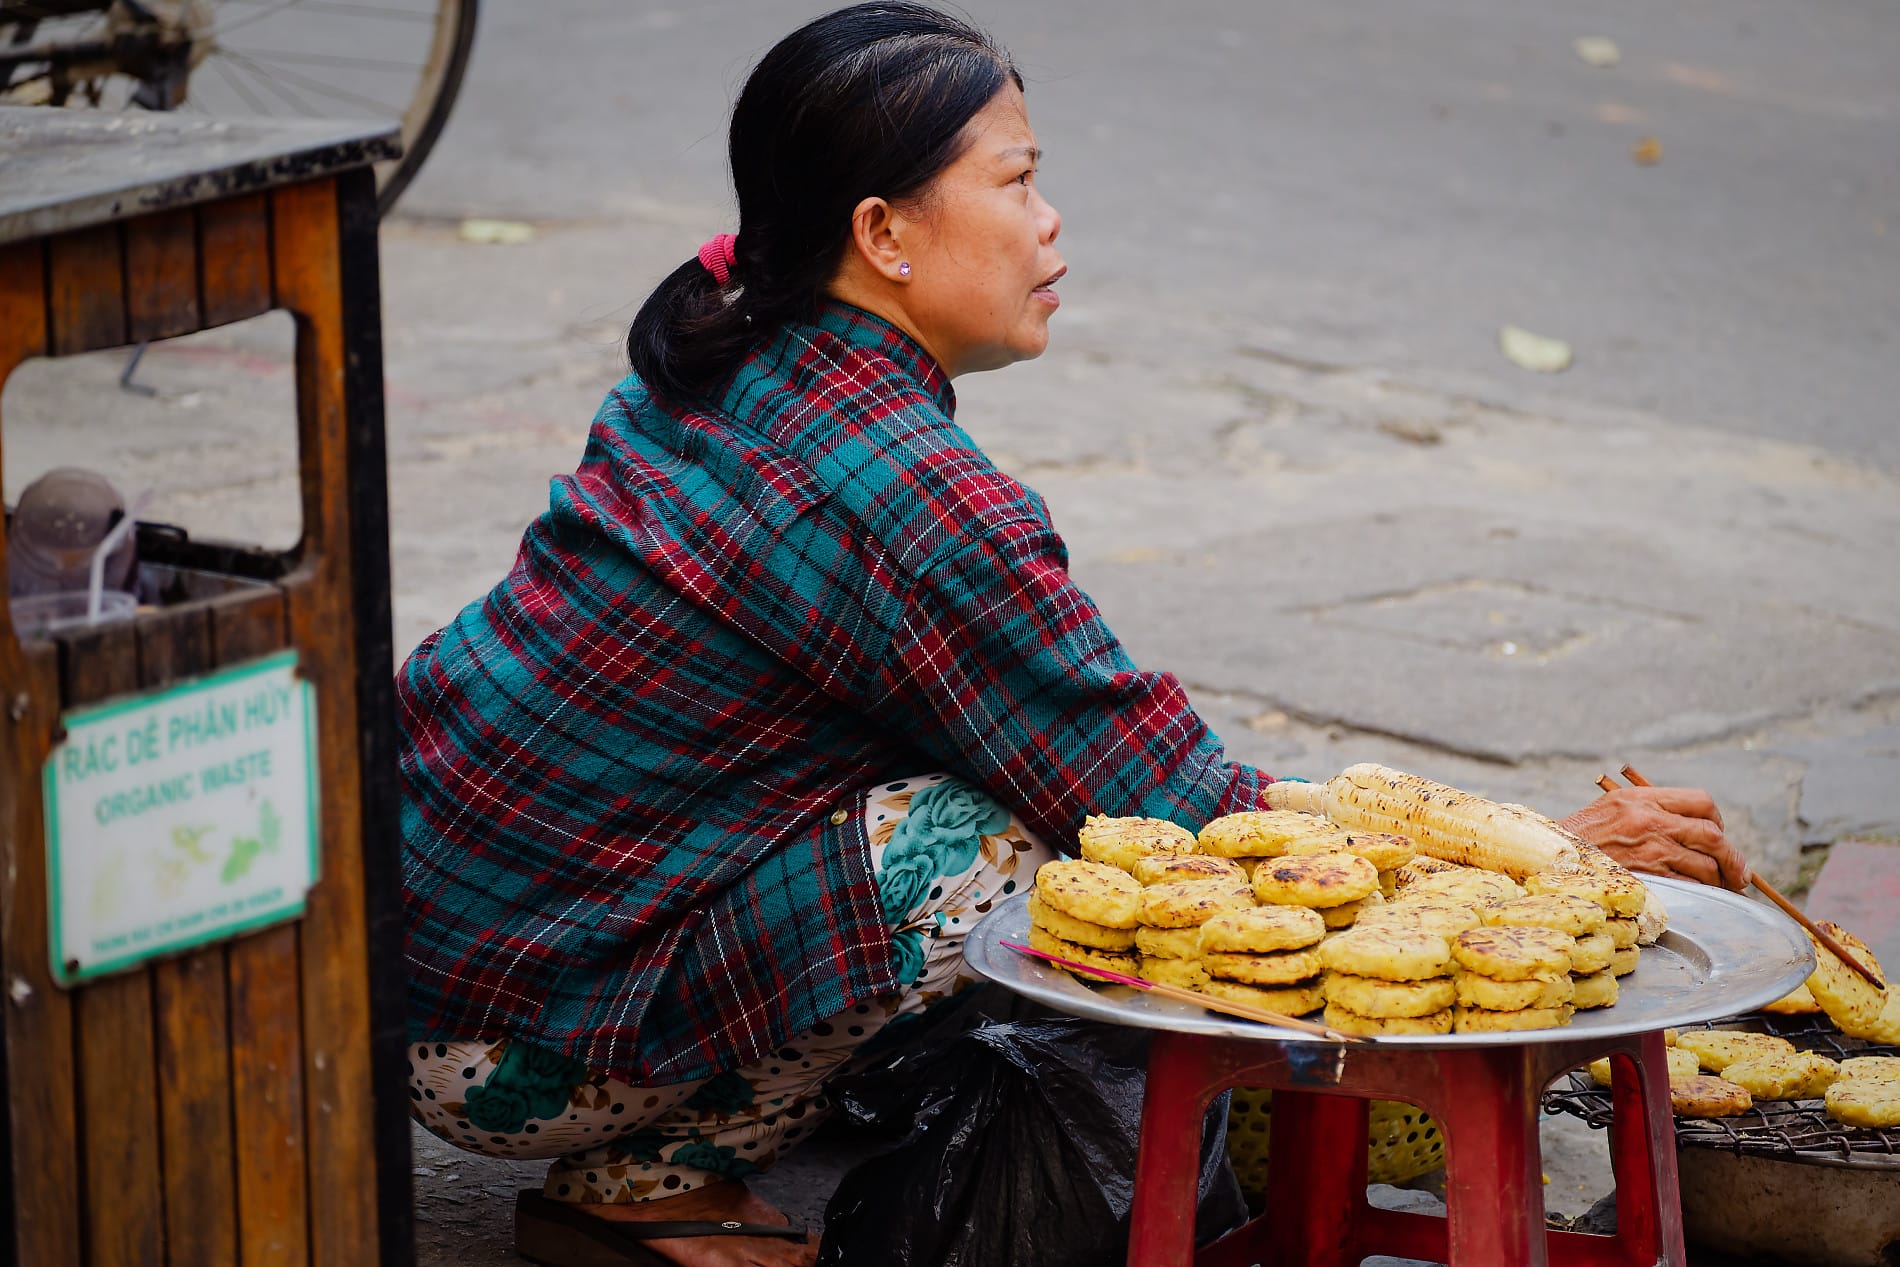
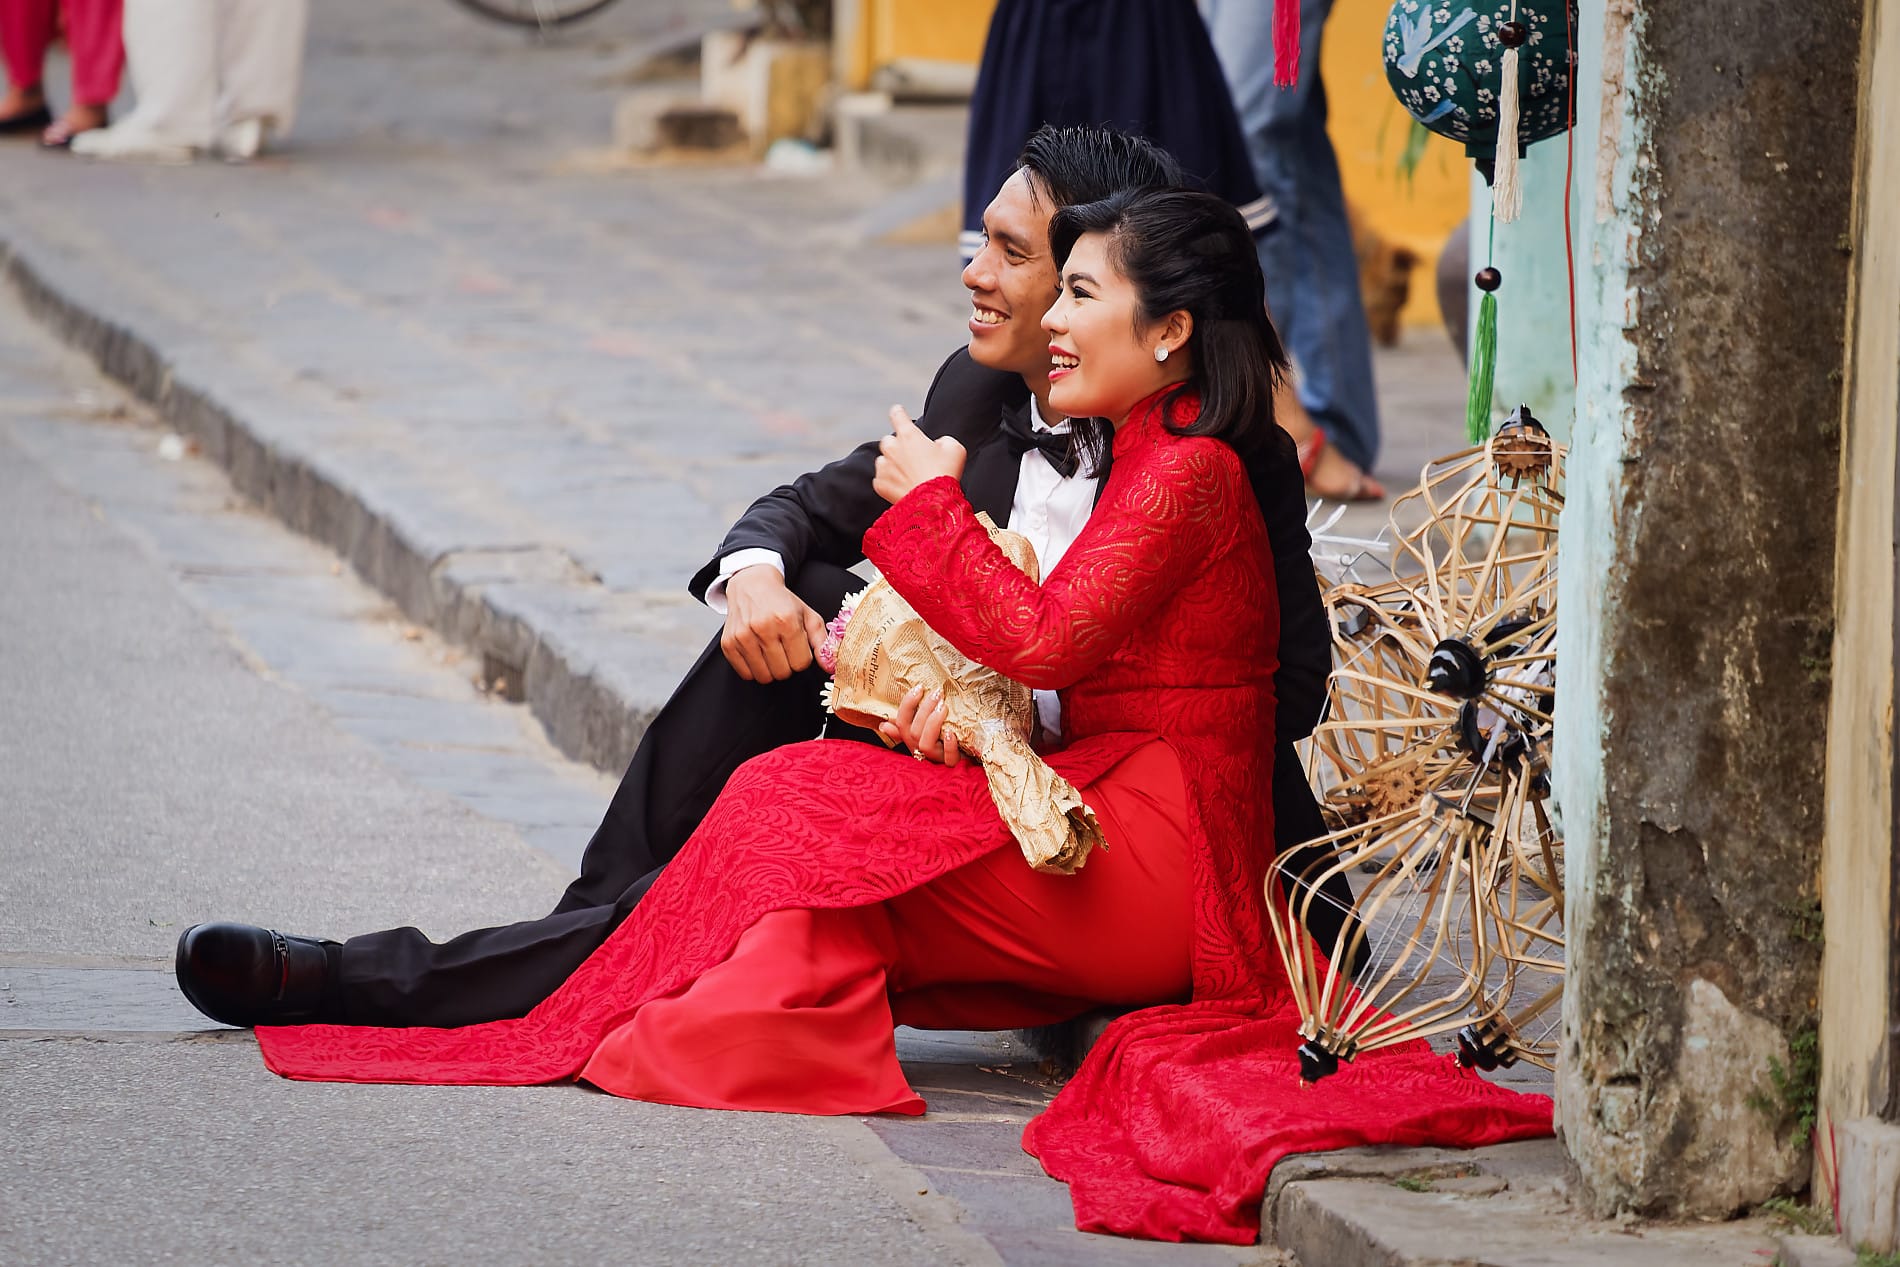
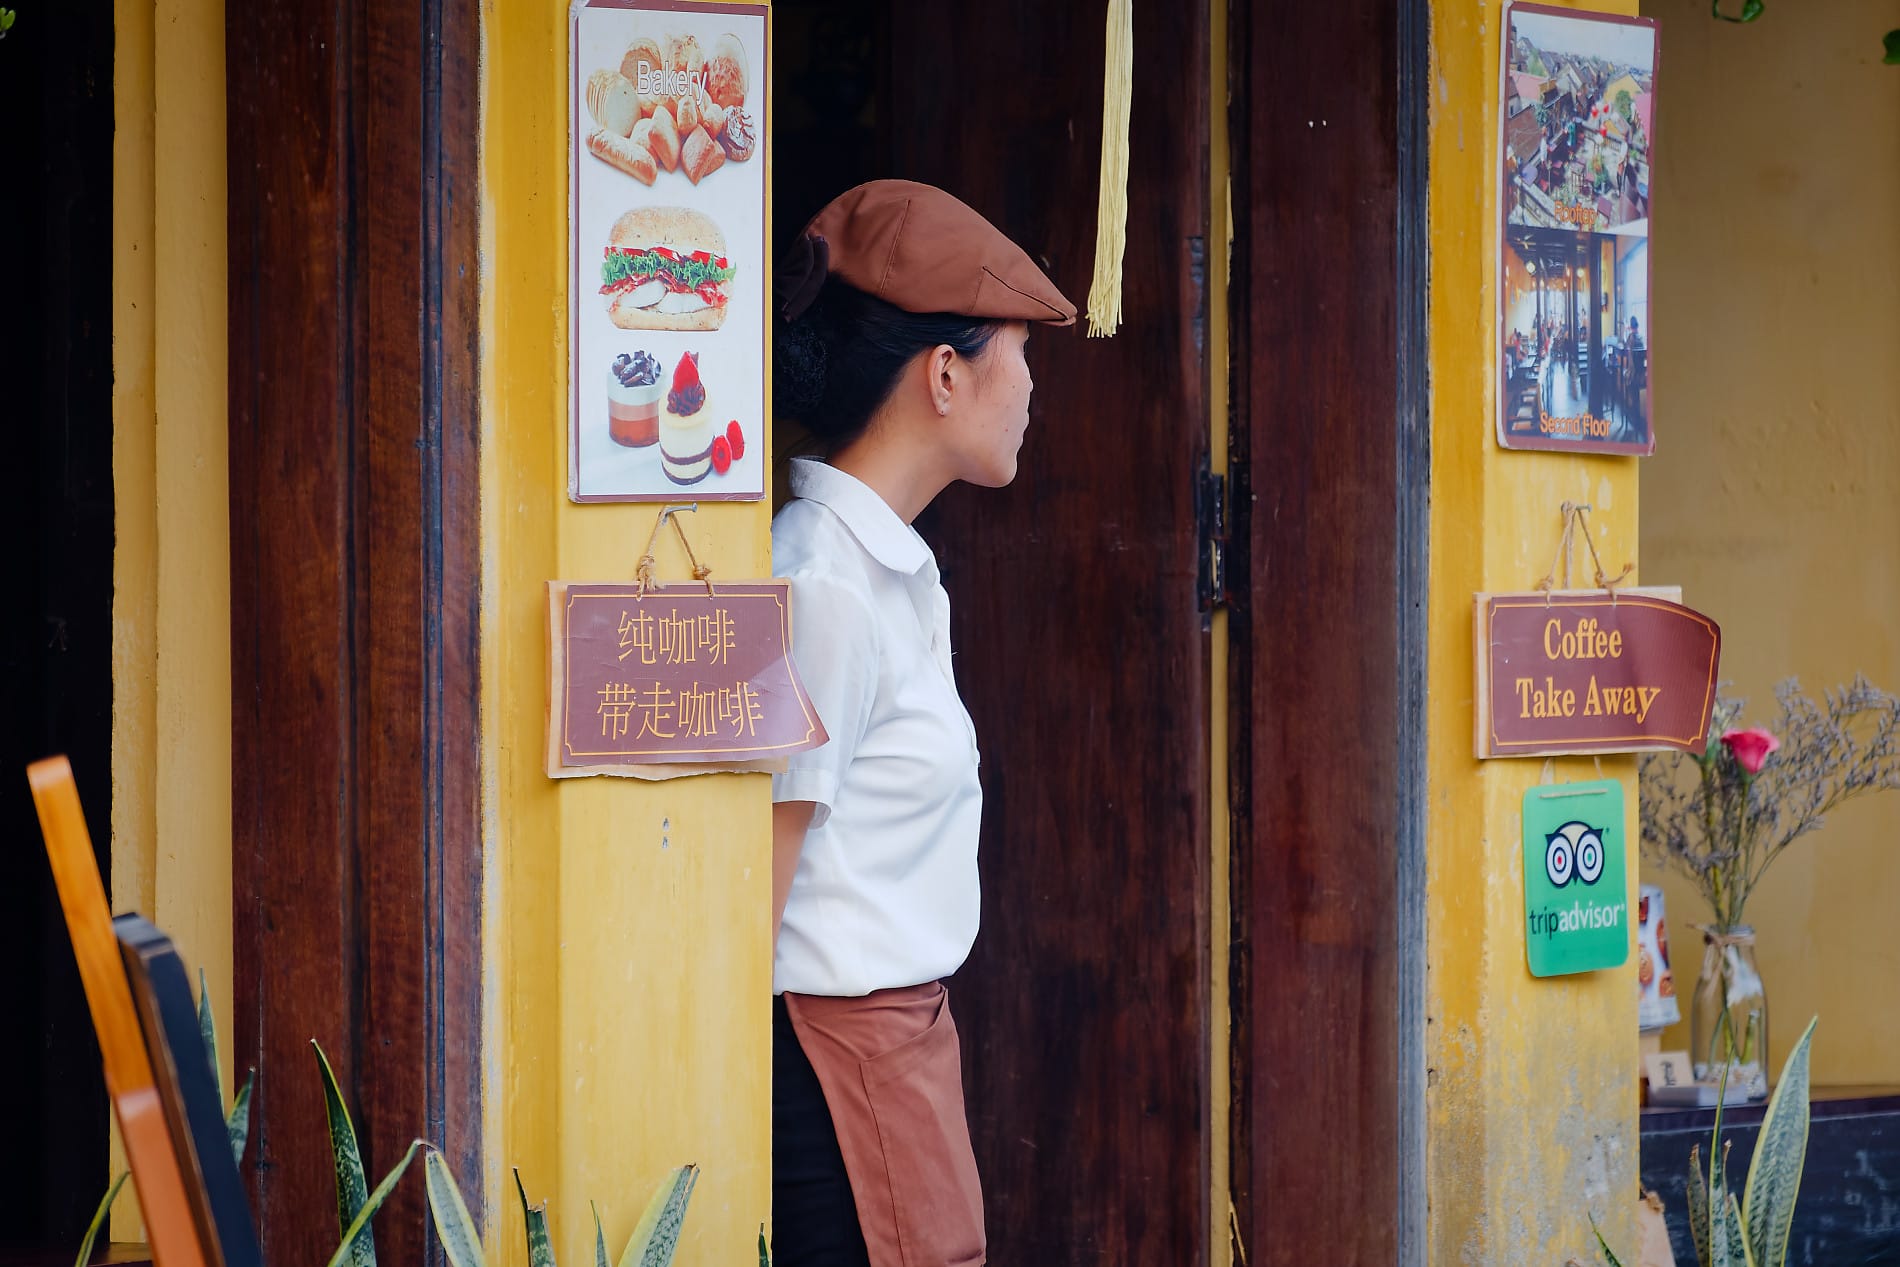
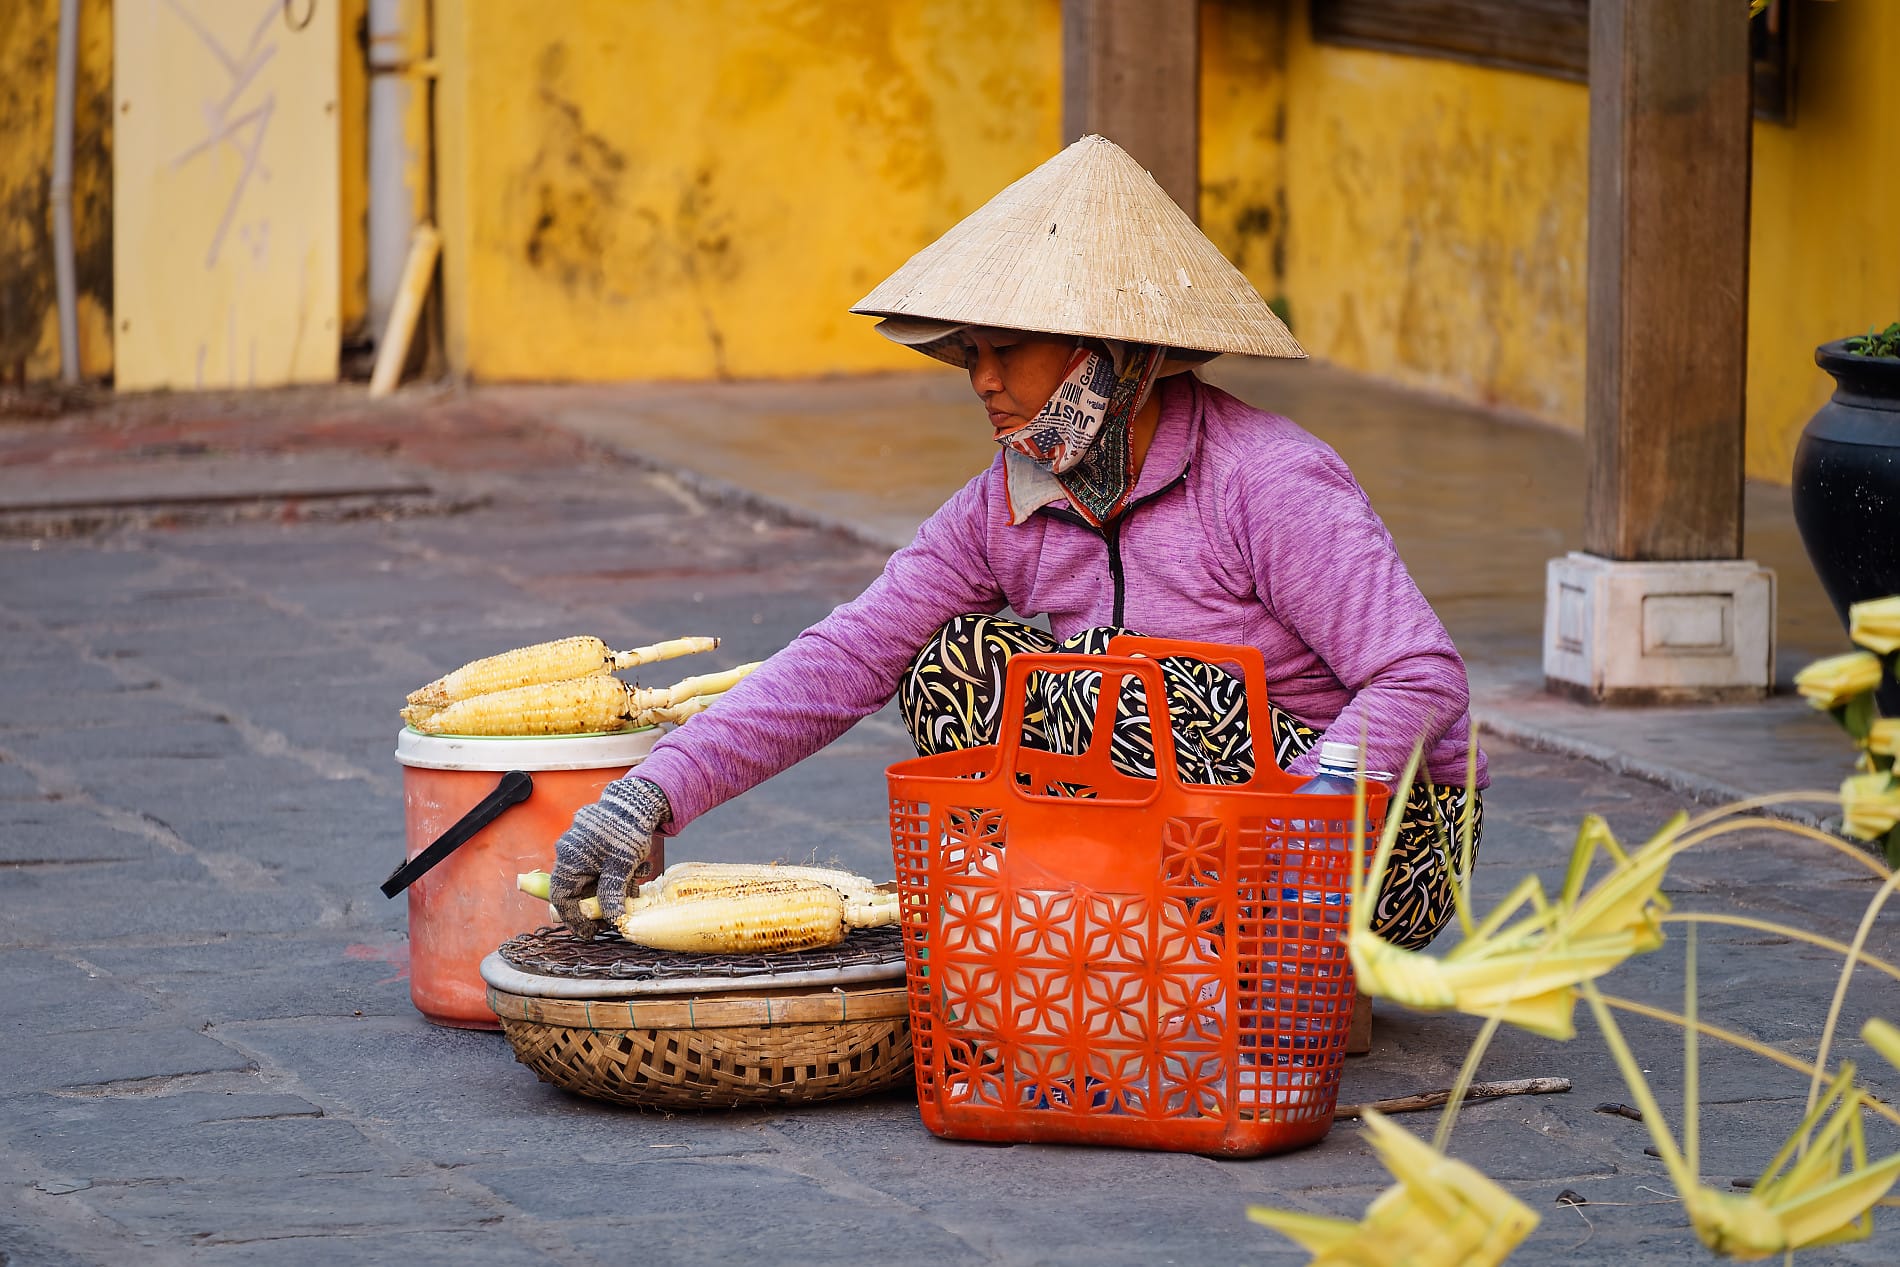
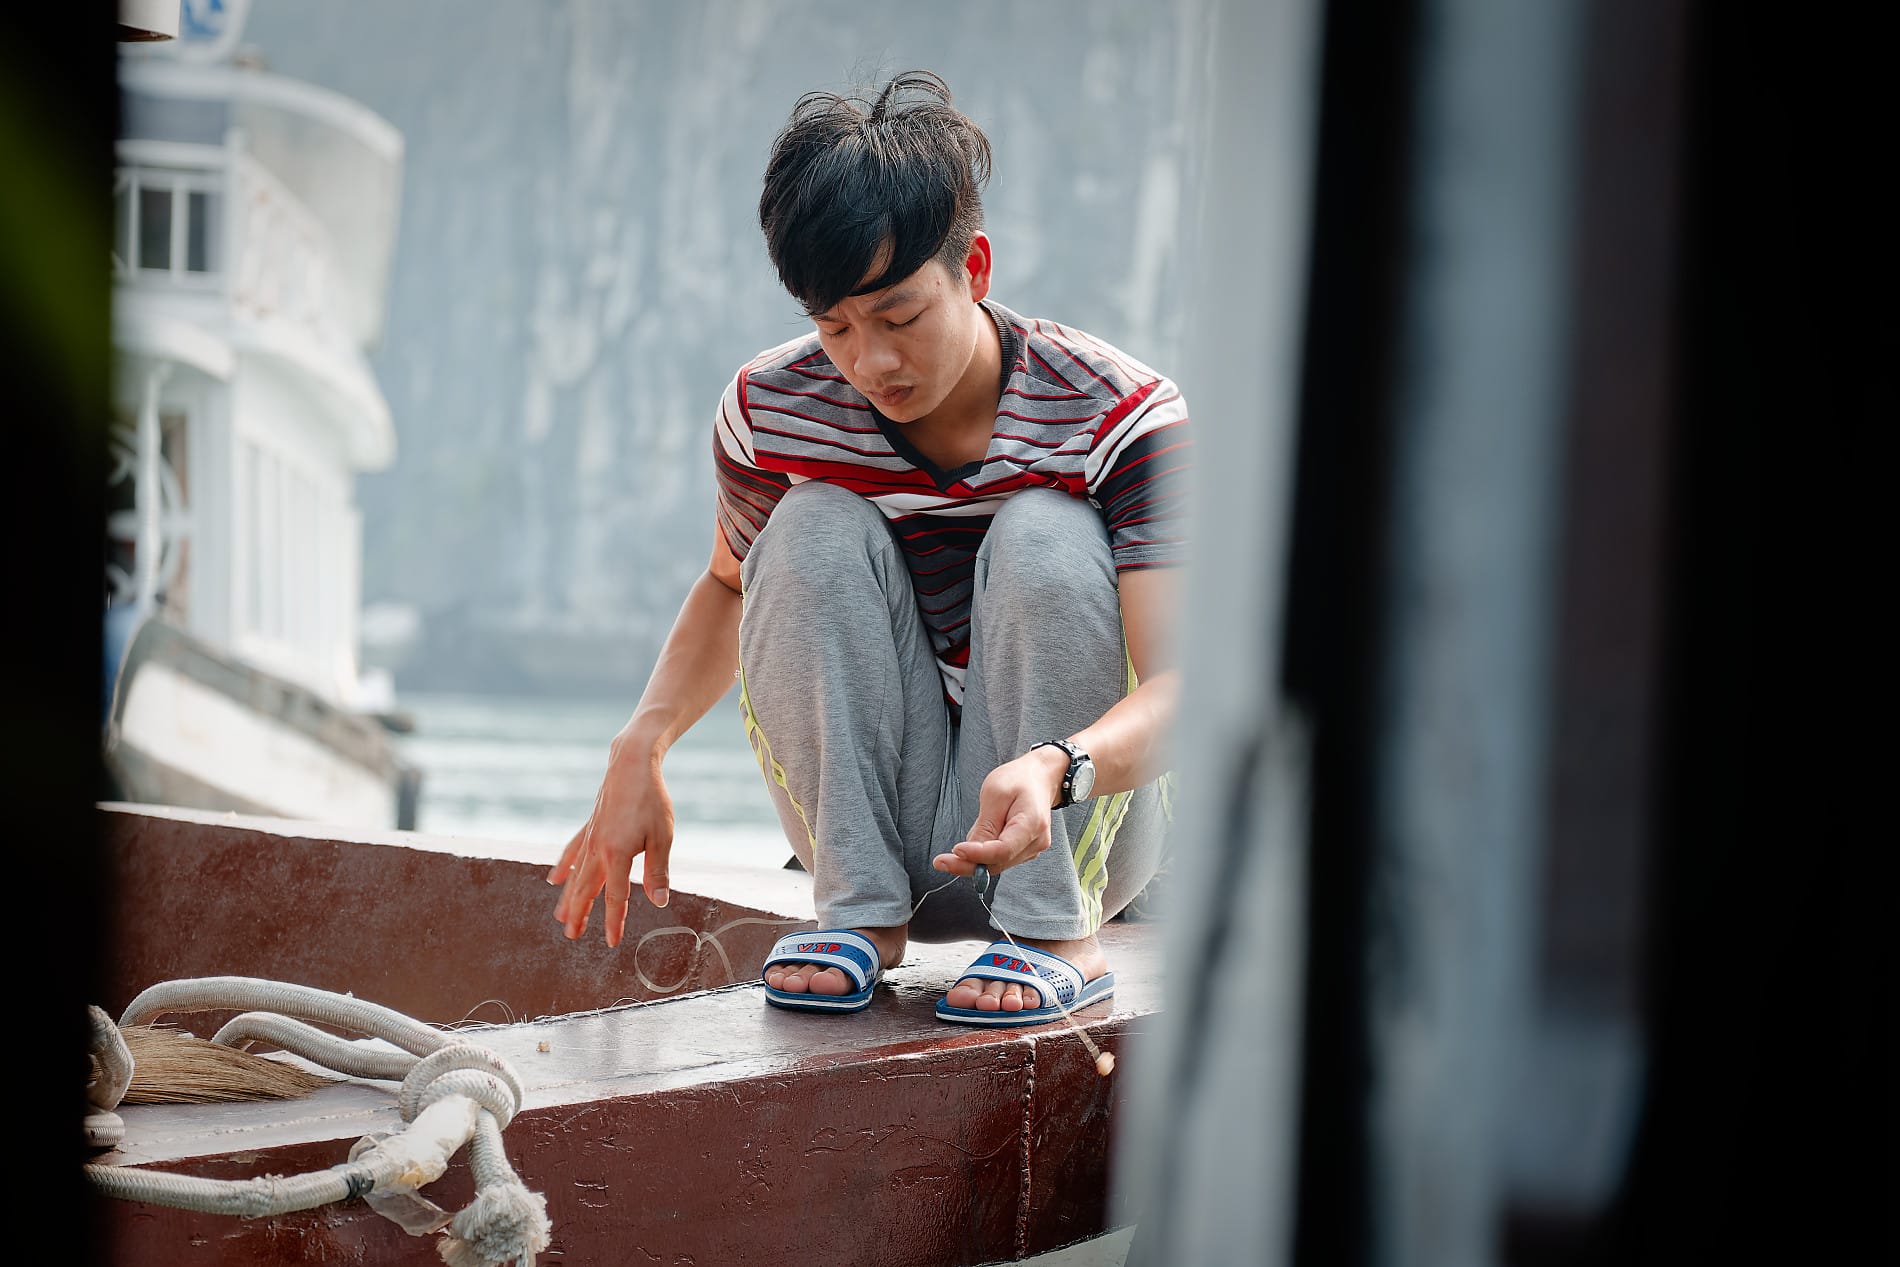
Преди точно десет години се озовах във Виетнам. Една страна, която буквално живее на улицата. Улицата е бизнес, прехрана, в най-буквалния смисъл – и за тези, които присядат на малко столче и хапват топла супа или някаква друга популярна улична храна, и за тези, които изкарват прехраната си, приготвяйки и предлагайки такава храна. На мотопед, велосипед или пеша, виетнамецът е на улицата повече време, отколкото вкъщи или някъде другаде. Улицата там е сцена на самия живот.
Кадри от улиците на Ханой, Хой Ан, Ми Сън и Ха Лонг
Когато снимам хора на улицата обикновено не публикувам снимките веднага и това е нарочно, за да оставя достатъчно време „уловеният“ момент да се раздалечи във времето от неговото публично разкриване. Но признавам, че цели десет години разстояние е твърде много, най-малкото защото историите зад кадрите започват да избледняват в паметта ми.
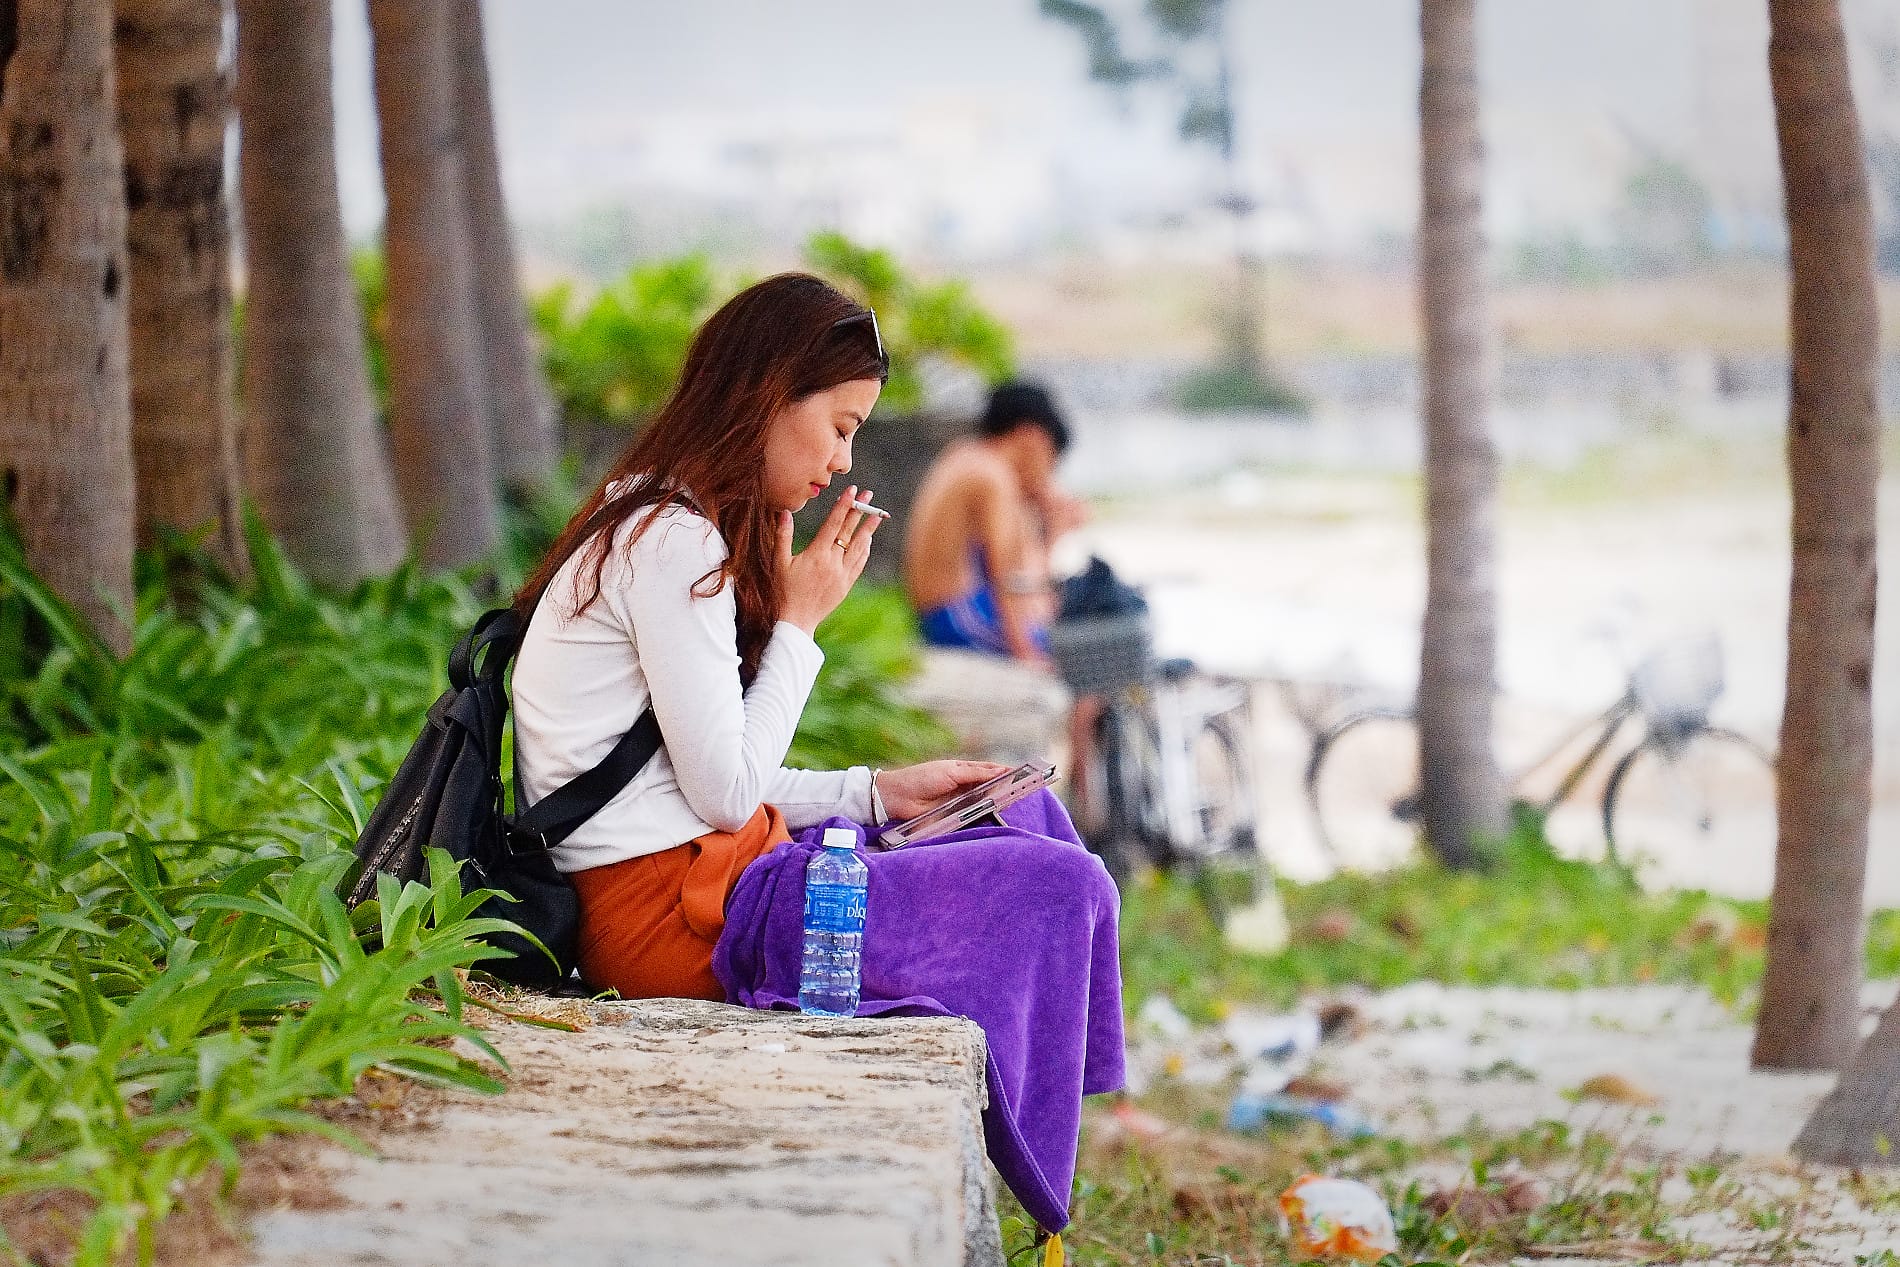
Момичето с цигарата на заглавната снимка не е виетнамка. Туристка е, от смесен произход, тръгнала на обиколка из тези места, водена от желанието да научи повече за корените си. Докато снимах кадъра по-долу, жена ми я беше заприказвала. Но не помня нищо повече от нейната история.
И двете снимки са някъде от безкрайните плажове около Да Нанг.
До 29-ти септември в полунощ българите зад граница могат да подават заявления за гласуване в секциите в чужбина. Дори с последните промени в Изборния кодекс тези заявления са особено важни предвид рекордно ниския брой автоматично одобрени секции, с които бяхме свикнали на предходните няколко вота.
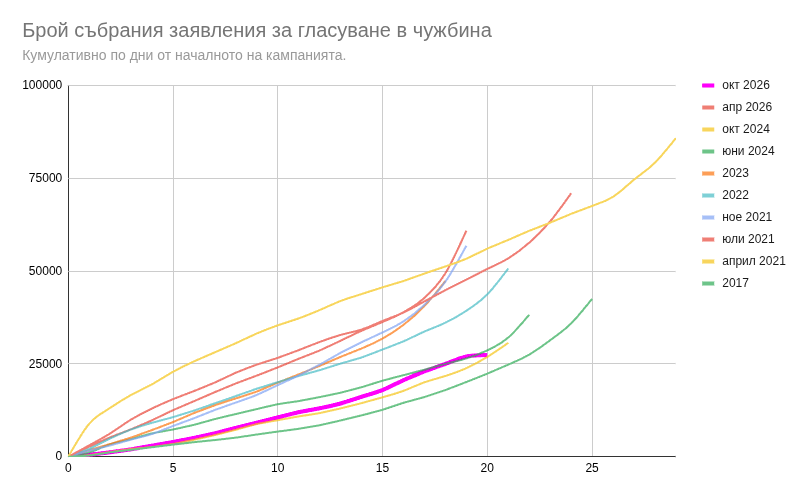
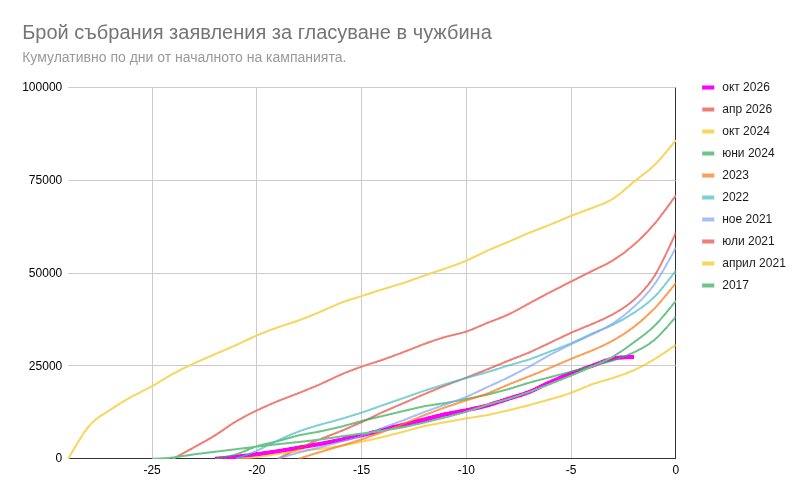
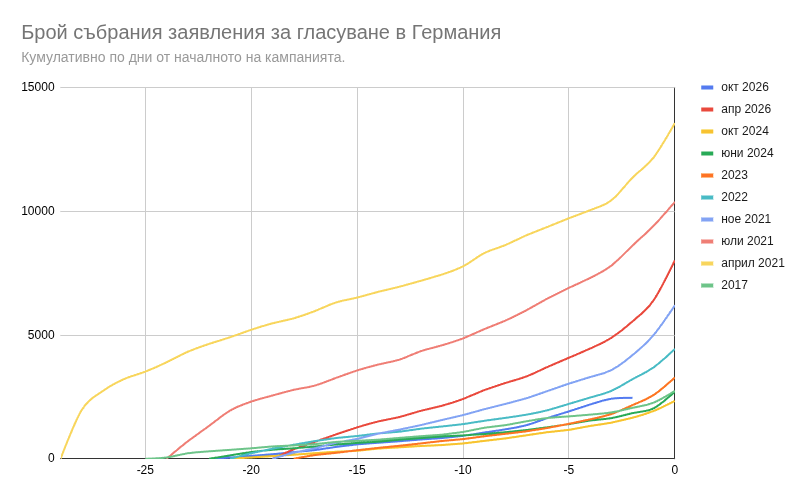
На 15-ти септември писах за напредъка в рамките на първата седмица. Преди това писах защо е важно, а през март – често за срещани грешки в попълването. Два дни и половина преди крайния срок има около 27500 подадени заявления. Това е рекордно малък брой спрямо последните десет години като изключим изборите през октомври 2024, когато имаше много автоматично обявени секции и заявленията не бяха толкова важни за отварянето им.
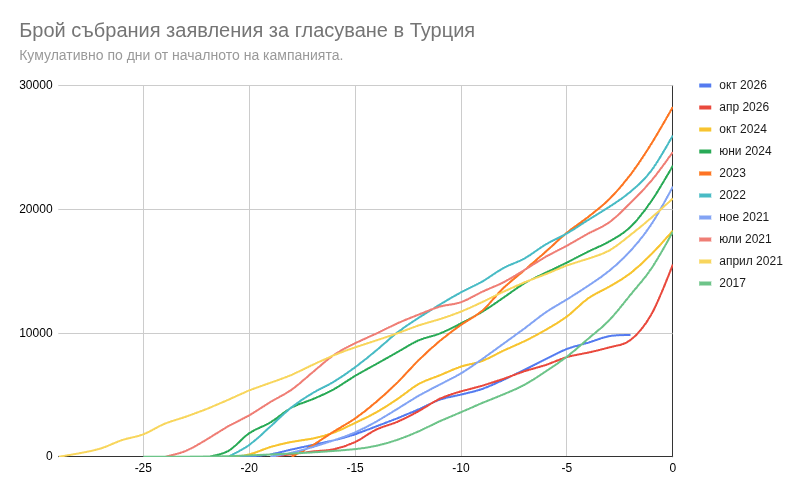
Сравнение на броя заявление към 20-ти я ден от подаването им като кампаниите са с различна продължителностСравнение на броя заявления спрямо дни преди крайния срок
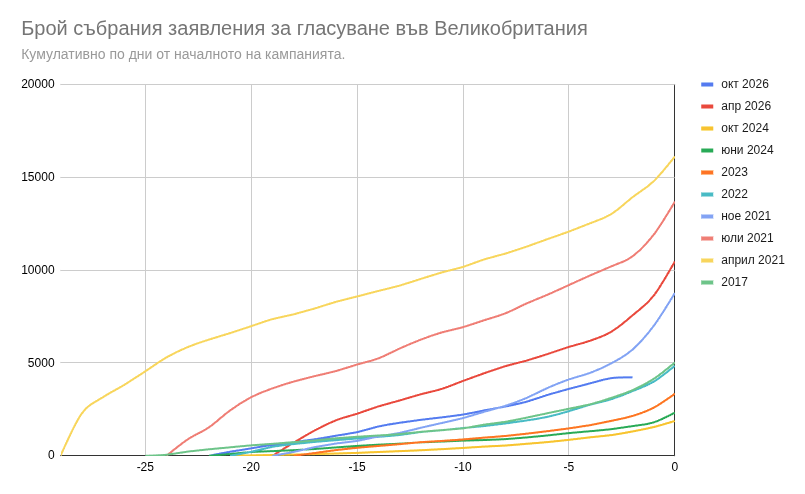
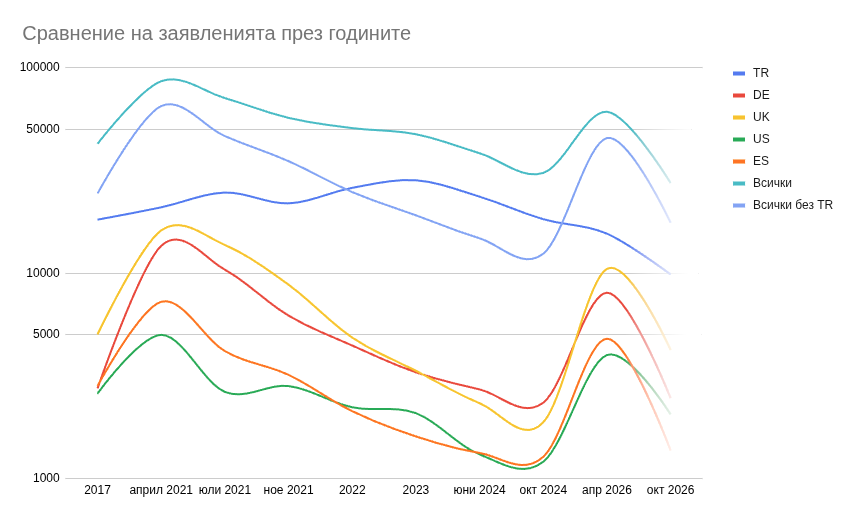
Сега обаче ситуацията е различна особено за българите извън Европейския съюз, където се отварят секции само в дипломатическите представителства или със заявление. Във Великобритания виждаме сравнително висока активност спрямо вотовете между 2022 и 2024, но двойно и тройно по-ниска от изборите през април 2026 и тези през 2021-ва.
В Германия картината е подобна, но говорим за два до пет пъти по-малко от годините със силна активност. В Германия се очаква да има по-малко секции от минали години по тази причина.
Както съм показвал преди, кривите на активността на подаване на заявления в Турция традиционно са различни от всички други държави. Това е индикация за различно поведение. През двата вота тази година обаче това не е така. Освен, че има значително по-малко заявления, активността следва траекторията на всички останали български диаспори.
Предварително сравнение на броя заявления между изборите в последните 10 години показва, че ще има значително намаление не само спрямо април, но и спрямо предишните президентски избори. Вижда се ясно намалението в активността в Турция от 2023 до сега. Заради промените в Избирателния кодекс има повече активност в САЩ и Великобритания, видимо доста по-малко от април.
Когато завърши кампанията и обявят секциите зад граница, ще направя нова карта с тях и адресите им. Виждам, че МВнР готви вече своя карта, което е добре. Ще пусна и съвети и обяснение за казуси особено предвид, че има значителна несигурност за гласуването в чужбина при балотажа. Забелязах обаче и притеснителни индикации, че са си решили къде да са секциите в чужбина още преди диаспорите ни да имат възможност да заявят желанието си и да се организират. За сега това е само съмнение, което се надявам да отхвърля когато публикуват решението за секциите.
This week Qualcomm unveiled its next generation of high-end mobile SoCs: Snapdragon 8 Elite Gen 6, and Elite Extreme Gen 6. The flagship chips bring a slew of new features to the table, including new Oryon CPU cores, GPU matrix cores, and LPDDR6 support
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.