Post Syndicated from Ritesh Sinha original https://aws.amazon.com/blogs/big-data/harnessing-the-power-of-nested-materialized-views-and-exploring-cascading-refresh/
Amazon Redshift materialized views enables you to significantly improve performance of complex queries. Materialized views store precomputed query results that future similar queries can utilize, offering a powerful solution for data warehouse environments where applications often need to execute resource-intensive queries against large tables. This optimization technique enhances query speed and efficiency by allowing many computation steps to be skipped, with precomputed results returned directly. Materialized views are particularly useful for speeding up predictable and repeated queries, such as those used to populate dashboards or generate reports. Instead of repeatedly performing resource-intensive operations, applications can query a materialized view and retrieve precomputed results, leading to significant performance gains and improved user experience. Additionally, materialized views can be incrementally refreshed, applying logic only to changed data when data manipulation language (DML) changes are made to the underlying base tables, further optimizing performance and maintaining data consistency.
This post demonstrates how to maximize your Amazon Redshift query performance by effectively implementing materialized views. We’ll explore creating materialized views and implementing nested refresh strategies, where materialized views are defined in terms of other materialized views to expand their capabilities. This approach is particularly powerful for reusing precomputed joins with different aggregate options, significantly reducing processing time for complex ETL and BI workloads. Let’s explore how to implement this powerful feature in your data warehouse environment.
Introduction to Nested Materialized Views
Nested materialized views in Amazon Redshift allow you to create materialized views based on other materialized views. This capability enables a hierarchical structure of precomputed results, significantly enhancing query performance and data processing efficiency. With nested materialized views, you can build multi-layered data abstractions, creating increasingly complex and specialized views tailored to specific business needs.This layered approach offers several advantages:
- Improved Query Performance: Each level of the nested materialized view hierarchy serves as a cache, allowing queries to quickly access pre-computed data without the need to traverse the underlying base tables.
- Reduced Computational Load: By offloading the computational work to the materialized view refresh process, you can significantly reduce the runtime and resource utilization of your day-to-day queries.
- Simplified Data Modeling: Nested materialized views enable you to create a more modular and extensible data model, where each layer represents a specific business concept or use case.
- Incremental Refreshes: The Redshift materialized views support incremental refreshes, allowing you to update only the changed data within the nested hierarchy, further optimizing the refresh process.
- Cascading Materialized Views: The Redshift materialized views support automatic handling of Extract, Load, and Transform (ELT) style workloads, minimizing the need for manual creation and management of these processes.
You can implement nested materialized views using the CREATE MATERIALIZED VIEW statement, which allows referencing other materialized views in the definition. Common use cases include:
- Modular data transformation pipelines
- Hierarchical aggregations for progressive analysis
- Multi-level data validation pipelines
- Historical data snapshot management
- Optimized BI reporting with precomputed results
Architecture

Architectural diagram depicting Amazon Redshift’s nested materialized view structure. Shows multiple base tables (orange) connecting to materialized views (red), with connections to a nested view layer and data sharing table (green). Includes integration points for users and QuickSight visualization.
- Base Table(s): These are the underlying base tables that contain the raw data for your data warehouse. It can be local tables or data sharing tables.
- Base Materialized View(s): These are the first-level materialized views that are created directly on top of the base tables. These views encapsulate common data transformations and aggregations. This can serve as the base for the nested materialized view and also be accessed by users directly.
- Nested Materialized View(s): These are the second level (or higher) materialized views that are created based on the base materialized views. The nested materialized view can further aggregate, filter, or transform the data from the base materialized views.
- Application/Users/BI Reporting: The application or business intelligence (BI) tools interact with the nested materialized views to generate reports and dashboards. The nested views provide a more optimized and precomputed data structure for efficient querying and reporting.
Creating and using nested materialized views
To demonstrate how nested materialized views work in Amazon Redshift, we’ll use the TPC-DS dataset. We’ll create three queries using the STORE, STORE_SALES, CUSTOMER, and CUSTOMER_ADDRESS tables to simulate data warehouse reports. This example will illustrate how multiple reports can share result sets and how materialized views can improve both resource efficiency and query performance.Let’s consider the following queries as dashboard queries:
SELECT cust.c_customer_id,
cust.c_first_name,
cust.c_last_name,
sales.ss_item_sk,
sales.ss_quantity,
cust.c_current_addr_sk
FROM store_sales sales INNER JOIN customer cust
ON sales.ss_customer_sk = cust.c_customer_sk;

SELECT cust.c_customer_id,
cust.c_first_name,
cust.c_last_name,
sales.ss_item_sk,
sales.ss_quantity,
cust.c_current_addr_sk,
store.s_store_name
FROM store_sales sales INNER JOIN customer cust
ON sales.ss_customer_sk = cust.c_customer_sk
INNER JOIN store store
ON sales.ss_store_sk = store.s_store_sk;

SELECT cust.c_customer_id,
cust.c_first_name, cust.c_last_name,
sales.ss_item_sk,
sales.ss_quantity,
addr.ca_state
FROM store_sales sales INNER JOIN customer cust
ON sales.ss_customer_sk = cust.c_customer_sk
INNER JOIN store store
ON sales.ss_store_sk = store.s_store_sk
INNER JOIN customer_address addr
ON cust.c_current_addr_sk = addr.ca_address_sk;
Notice that the join between STORE_SALES and CUSTOMER tables is present at all 3 queries (dashboards).
The second query adds a join with STORE table and the third query is the second one with an extra join with CUSTOMER_ADDRESS table. This pattern is common in business intelligence scenarios. As mentioned earlier, using a materialized view can speed up queries because the result set is stored and ready to be delivered to the user, avoiding reprocessing of the same data. In cases like this, we can use nested materialized views to reuse already processed data.When transforming our queries into a set of nested materialized views, the result would be as below:
CREATE MATERIALIZED VIEW StoreSalesCust as
SELECT cust.c_customer_id,
cust.c_first_name,
cust.c_last_name,
sales.ss_item_sk,
sales.ss_store_sk,
sales.ss_quantity,
cust.c_current_addr_sk
FROM store_sales sales INNER JOIN customer cust
ON sales.ss_customer_sk = cust.c_customer_sk;

CREATE MATERIALIZED VIEW StoreSalesCustStore as
SELECT storesalescust.c_customer_id,
storesalescust.c_first_name,
storesalescust.c_last_name,
storesalescust.ss_item_sk,
storesalescust.ss_quantity,
storesalescust.c_current_addr_sk,
store.s_store_name
FROM StoreSalesCust storesalescust INNER JOIN store store
ON storesalescust.ss_store_sk = store.s_store_sk;

CREATE MATERIALIZED VIEW StoreSalesCustAddress as
SELECT storesalescuststore.c_customer_id,
storesalescuststore.c_first_name,
storesalescuststore.c_last_name,
storesalescuststore.ss_item_sk,
storesalescuststore.ss_quantity,
addr.ca_state
FROM StoreSalesCustStore storesalescuststore INNER JOIN customer_address addr
ON storesalescuststore.c_current_addr_sk = addr.ca_address_sk;
Nested materialized views can improve performance and resource efficiency by reusing initial view results, minimizing redundant joins, and working with smaller result sets. This creates a hierarchical structure where materialized views depend on one another. Due to these dependencies, you must refresh the views in a specific order.

SQL query result indicating dependency issue for REFRESH MATERIALIZED VIEW StoreSalesCustAddress.
With the new option “REFRESH MATERIALIZED VIEW mv_name CASCADE” you will be able to refresh the entire chain of dependencies for the materialized views you have. Note that in this example we are using the third materialized view, StoreSalesCustAddress, and this will refresh all 3 materialized views because they are dependent on each other.

SQL query showing successful CASCADE refresh of StoreSalesCustAddress materialized view in Amazon Redshift.
If we use the second materialized view with the CASCADE option, we will refresh only the first and second materialized views, leaving the third unchanged. This may be useful when we need to keep some materialized views with less current data than others.
The SVL_MV_REFRESH_STATUS system view reveals the refresh sequence of materialized views. When triggering a cascade refresh on StoreSalesCustAddress, the system follows the dependency chain we established: StoreSalesCust refreshes first, followed by StoreSalesCustStore, and finally StoreSalesCustAddress. This demonstrates how the refresh operation respects the hierarchical structure of our materialized views.

SQL query result from SVL_MV_REFRESH_STATUS showing successful recomputation of three materialized views.
Considerations
Consider a dependency chain where StoreSalesCust (A) → StoreSalesCustStore (B) → StoreSalesCustAddress (C).
- The CASCADE refresh behavior works as follows:
- When refreshing C with CASCADE: A, B, and C will all be refreshed.
- When refreshing B with CASCADE: Only A and B will be refreshed.
- When refreshing A with CASCADE: Only A will be refreshed.
- If you specifically need to refresh A and C but not B, you must perform separate refresh operations without using CASCADE—first refresh A, then refresh C directly.
Best Practices for Materialized View
- Improve the source query: Start with a well-optimized SELECT statement for your materialized view. This is especially important for views that need full rebuilds during each refresh.
- Plan refresh strategies: When creating materialized views that depend on other materialized views, you cannot use AUTO REFRESH YES. Instead, implement orchestrated refresh mechanisms using Redshift Data API with Amazon EventBridge for scheduling and AWS Step Functions for workflow management.
- Leverage distribution and sort keys: Properly configure distribution and sort keys on materialized views based on their query patterns to optimize performance. Well-chosen keys improve query speed and reduce I/O operations.
- Consider incremental refresh capability: When possible, design materialized views to support incremental refresh, which only updates changed data rather than rebuilding the entire view, greatly improving refresh performance.
- To learn more about the Automated materialized view (auto-MV) feature to boost your workload performance, this intelligent system monitors your workload and automatically creates materialized views to enhance overall performance. For more detailed information on this feature, please refer to Automated materialized views.
Clean up
Complete the following steps to clean up your resources:
- Delete the Redshift provisioned replica cluster or the Redshift serverless endpoints created for this exercise
or
- Drop only the Materialized view which you have created for testing
Conclusion
This post showed how to create nested Amazon Redshift materialized views and refresh the child materialized views using the new REFRESH CASCADE option. You can quickly build and maintain efficient data processing pipelines and seamlessly extend the low latency query execution benefits of materialized views to data analysis.
About the authors
 Ritesh Kumar Sinha is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.
 Raza Hafeez is a Senior Product Manager at Amazon Redshift. He has over 13 years of professional experience building and optimizing enterprise data warehouses and is passionate about enabling customers to realize the power of their data. He specializes in migrating enterprise data warehouses to AWS Modern Data Architecture.
 Ricardo Serafim is a Senior Analytics Specialist Solutions Architect at AWS. He has been helping companies with Data Warehouse solutions since 2007.


 Jeremy Spell is a Cloud Infrastructure Architect working with Amazon Web Services (AWS) Professional Services. He enjoys architecting and building solutions for customers. In his free time Jeremy makes Texas style BBQ, and spends time with his family and church community.
 Jeff Demuth is a solutions architect who joined Amazon Web Services (AWS) in 2016. He focuses on the geospatial community and is passionate about geographic information systems (GIS) and technology. Outside of work, Jeff enjoys traveling, building Internet of Things (IoT) applications, and tinkering with the latest gadgets.


 Raks Khare is a Senior Analytics Specialist Solutions Architect at AWS based out of Pennsylvania. He helps customers across varying industries and regions architect data analytics solutions at scale on the AWS platform. Outside of work, he likes exploring new travel and food destinations and spending quality time with his family.
 Ritesh Kumar Sinha is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.
 Yanzhu Ji is a Product Manager in the Amazon Redshift team. She has experience in product vision and strategy in industry-leading data products and platforms. She has outstanding skill in building substantial software products using web development, system design, database, and distributed programming techniques. In her personal life, Yanzhu likes painting, photography, and playing tennis.
 Harshida Patel is a Analytics Specialist Principal Solutions Architect, with AWS.


 Raghu Kuppala is an Analytics Specialist Solutions Architect experienced working in the databases, data warehousing, and analytics space. Outside of work, he enjoys trying different cuisines and spending time with his family and friends.
 Sumant Nemmani is a Senior Technical Product Manager at AWS. He is focused on helping customers of Amazon Redshift benefit from features that use machine learning and intelligent mechanisms to enable the service to self-tune and optimize itself, ensuring Redshift remains price-performant as they scale their usage.
 Gagan Goel is a Software Development Manager at AWS. He ensures that Amazon Redshift features meet customer needs by prioritising and guiding the team in delivering customer-centric solutions, monitor and enhance query performance for customer workloads.
 Kshitij Batra is a Software Development Engineer at Amazon, specializing in building resilient, scalable, and high-performing software solutions.
 Sanuj Basu is a Principal Engineer at AWS, driving the evolution of Amazon Redshift into a next-generation, exabyte-scale cloud data warehouse. He leads engineering for Redshift’s core data platform — including managed storage, transactions, and data sharing — enabling customers to power seamless multi-cluster analytics and modern data mesh architectures. Sanuj’s work helps Redshift customers break through th


 Konstantina Mavrodimitraki is a Senior Solutions Architect at Amazon Web Services, where she assists customers in designing scalable, robust, and secure systems in global markets. With deep expertise in data strategy, data warehousing, and big data systems, she helps organizations transform their data landscapes. A passionate technologist and people person, Konstantina loves exploring emerging technologies and supports the local tech communities. Additionally, she enjoys reading books and playing with her dog.
 Kostas Diamantis is the Head of the Data Warehouse at Skroutz company. With a background in software engineering, he transitioned into data engineering, using his technical expertise to build scalable data solutions. Passionate about data-driven decision-making, he focuses on optimizing data pipelines, enhancing analytics capabilities, and driving business insights.

 Donatas Kuchalskis is a Cloud Operations Architect at AWS, based in London, focusing on Financial Services customers in the UK. He helps customers optimize their AWS environments for cost, security, and resiliency while providing strategic cloud guidance. Prior to this role, he served as a Prototyping Architect specializing in Big Data and as a Specialist Solutions Architect for Retail. Before joining AWS, Donatas spent 6 years as a technical consultant in the retail sector.
 Jumana Nagaria is a Prototyping Architect at AWS. She builds innovative prototypes with customers to solve their business challenges. She is passionate about cloud computing and data analytics. Outside of work, Jumana enjoys travelling, reading, painting, and spending quality time with friends and family.


 If you select Redshift, you will be transferred to the Query editor where you can execute the SQL and see the results as shown in the following figure.

 Avijit Goswami is a Principal Data Solutions Architect at AWS specialized in data and analytics. He supports AWS strategic customers in building high-performing, secure, and scalable data lake solutions on AWS using AWS managed services and open-source solutions. Outside of his work, Avijit likes to travel, hike in the San Francisco Bay Area trails, watch sports, and listen to music.
 Saman Irfan is a Senior Specialist Solutions Architect focusing on Data Analytics at Amazon Web Services. She focuses on helping customers across various industries build scalable and high-performant analytics solutions. Outside of work, she enjoys spending time with her family, watching TV series, and learning new technologies.
 Sudarshan Narasimhan is a Principal Solutions Architect at AWS specialized in data, analytics and databases. With over 19 years of experience in Data roles, he is currently helping AWS Partners & customers build modern data architectures. As a specialist & trusted advisor he helps partners build & GTM with scalable, secure and high performing data solutions on AWS. In his spare time, he enjoys spending time with his family, travelling, avidly consuming podcasts and being heartbroken about Man United’s current state.


 Julia Beck is an Analytics Specialist Solutions Architect at AWS. She supports customers in validating analytics solutions by architecting proof of concept workloads designed to meet their specific needs.
 Scott St. Martin is a Solutions Architect at AWS who is passionate about helping customers build modern applications. Scott uses his decade of experience in the cloud to guide organizations in adopting best practices around operational excellence and reliability, with a focus the manufacturing and financial services spaces. Outside of work, Scott enjoys traveling, spending time with family, and playing piano.


 Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.
 Jonathan Katz is a Principal Product Manager – Technical on the Amazon Redshift team and is based in New York. He is a Core Team member of the open source PostgreSQL project and an active open source contributor, including PostgreSQL and the pgvector project.


 Nita Shah is an Analytics Specialist Solutions Architect at AWS based out of New York. She has been building data warehouse solutions for over 20 years and specializes in Amazon Redshift. She is focused on helping customers design and build enterprise-scale well-architected analytics and decision support platforms.
 Sushmita Barthakur is a Senior Data Solutions Architect at Amazon Web Services (AWS), supporting Strategic customers architect their data workloads on AWS. With a background in data analytics, she has extensive experience helping customers architect and build enterprise data lakes, ETL workloads, data warehouses and data analytics solutions, both on-premises and the cloud. Sushmita is based in Florida and enjoys traveling, reading and playing tennis.
 Jonathan Katz is a Principal Product Manager – Technical on the Amazon Redshift team and is based in New York. He is a Core Team member of the open source PostgreSQL project and an active open source contributor, including PostgreSQL and the pgvector project.


 Laura is an Identity Solutions Architect at AWS, where she thrives on helping customers overcome security and identity challenges. In her free time, she enjoys wreck diving and traveling around the world.


 Noritaka Sekiyama is a Principal Big Data Architect with Amazon Web Services (AWS) Analytics services. He’s responsible for building software artifacts to help customers. In his spare time, he enjoys cycling on his road bike.
 Stefano Sandonà is a Senior Big Data Specialist Solution Architect at Amazon Web Services (AWS). Passionate about data, distributed systems, and security, he helps customers worldwide architect high-performance, efficient, and secure data solutions.
 Derek Liu is a Senior Solutions Architect based out of Vancouver, BC. He enjoys helping customers solve big data challenges through Amazon Web Services (AWS) analytic services.
 Raj Ramasubbu is a Senior Analytics Specialist Solutions Architect focused on big data and analytics and AI/ML with Amazon Web Services (AWS). He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS. Raj provided technical expertise and leadership in building data engineering, big data analytics, business intelligence, and data science solutions for over 18 years prior to joining AWS. He helped customers in various industry verticals like healthcare, medical devices, life science, retail, asset management, car insurance, residential REIT, agriculture, title insurance, supply chain, document management, and real estate.
 Angel Conde Manjon is a Sr. EMEA Data & AI PSA, based in Madrid. He has previously worked on research related to data analytics and AI in diverse European research projects. In his current role, Angel helps partners develop businesses centered on data and AI.




 Sandeep Adwankar is a Senior Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.
 Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She enjoys building data mesh solutions and sharing them with the community.
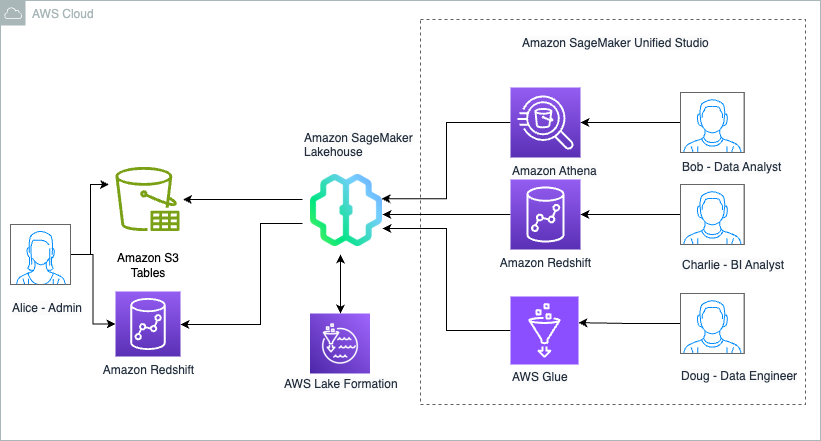




 Charlie can now further update the SQL query and use it to power QuickSight dashboards that can be shared with Sales team members.

 Sandeep Adwankar is a Senior Technical Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.
 Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.




 BP Yau is a Sr Partner Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.
 Ali Alladin is the Senior Director of Product Management and Partner Solutions at ThoughtSpot. In this role, Ali oversees Cloud Engineering and Operations, ensuring seamless integration and optimal performance of ThoughtSpot’s cloud-based services. Additionally, Ali spearheads the development of AI-powered solutions in augmented and embedded analytics, collaborating closely with technology partners to drive innovation and deliver cutting-edge analytics capabilities. With a robust background in product management and a keen understanding of AI technologies, Ali is dedicated to pushing the boundaries of what’s possible in the analytics space, helping organizations harness the full potential of their data.






 Yogesh Dhimate is a Sr. Partner Solutions Architect at AWS, leading technology partnership with Salesforce. Prior to joining AWS, Yogesh worked with leading companies including Salesforce driving their industry solution initiatives. With over 20 years of experience in product management and solutions architecture Yogesh brings unique perspective in cloud computing and artificial intelligence.
 Ife Stewart is a Principal Solutions Architect in the Strategic ISV segment at AWS. She has been engaged with Salesforce Data Cloud over the last 2 years to help build integrated customer experiences across Salesforce and AWS. Ife has over 10 years of experience in technology. She is an advocate for diversity and inclusion in the technology field.
 Mike Patterson is a Senior Customer Solutions Manager in the Strategic ISV segment at AWS. He has partnered with Salesforce Data Cloud to align business objectives with innovative AWS solutions to achieve impactful customer experiences. In his spare time, he enjoys spending time with his family, sports, and outdoor activities.
 Drew Loika is a Director of Product Management at Salesforce and has spent over 15 years delivering customer value via data platforms and services. When not diving deep with customers on what would help them be more successful, he enjoys the acts of making, growing, and exploring the great outdoors.




 Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specialized in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.