Security updates for Tuesday

Post Syndicated from jzb original https://lwn.net/Articles/1093144/

Security updates have been issued by AlmaLinux (expat, git-lfs, grafana-pcp, kernel-rt, python3.14-cryptography, redis:6, skopeo, and xmlrpc-c), Debian (jbig2dec and strongswan), Fedora (baresip, chirp, chromium, corosync, emacs, GitPython, libre, libsoup3, nsd, perl-Net-OAuth, and perl-XML-Bare), Mageia (apache-mod_auth_openidc, exiv2, freerdp, python-pyasn1, and tor), Red Hat (buildah, cockpit-image-builder, container-tools:rhel8, containernetworking-plugins, delve, linux-sgx, osbuild-composer, pcs, and runc), SUSE (amazon-cloudwatch-agent, aws-nitro-enclaves-cli, bzip2, c-ares, curl, dracut, emacs, fuse-overlayfs, gegl, GraphicsMagick, httpcomponents-client, java-1_8_0-openjdk, java-25-openjdk, lcms2, libidn, libusb-1_0, LibVNCServer, microcode_ctl, multipath-tools, NetworkManager, nghttp2, openexr, openssl-1_1, openssl-3, perl-URI, php-composer2, postgresql15, postgresql17, postgresql18, python-GitPython, python-tornado6, python313-pip, redis, redis7, ucode-intel, wget, and wireshark), and Ubuntu (gzip and php7.0).

Automatic Key Exchange: faster, post-quantum secure origin handshakes for 45 billion daily connections (and counting)

Post Syndicated from Suleman Ahmad original https://blog.cloudflare.com/automatic-key-exchange-for-origins/

Every time Cloudflare opens a new TLS 1.3 connection to an origin server, we have to make a guess: the protocol requires us to commit to a key agreement algorithm in the very first packet we send, before the origin has told us anything about itself or what it can support. If we guess right, the handshake completes in one round trip. Guess wrong, and the origin replies with a HelloRetryRequest, we start over, and the connection costs two round trips.

For years, our guess was the same for every origin on the Internet: X25519. Widely supported, but as it turns out, suboptimal for roughly 30% of the origin connections we've since measured.

Today we're announcing Automatic Key Exchange, an extension of Automatic SSL/TLS that replaces the guess with a measurement. We probe each origin to learn which key agreement algorithms it supports and prefers, then lead with that algorithm on the first try, preferring the post-quantum hybrid X25519MLKEM768 wherever the origin can speak it. 

With the ongoing rollout of Automatic Key Exchange across origin connections, HelloRetryRequests fell from roughly 52% to 3.7%, cutting more than 150 ms off connection handshake latency at p90. In addition, as part of our ongoing rollout, hundreds of thousands of domains now have post-quantum origin connections that nobody had to configure, with that number growing daily.

While the milliseconds are important, that second part may matter more. Somewhere right now, an adversary is recording encrypted traffic it can't read yet, betting that it will be able to in the future (an attack known as harvest-now, decrypt-later). Cloudflare is sprinting to make the Internet quantum-secure by 2029, the year some industry experts estimate classical encryption algorithms could be breached. That day has a name: Q-Day. Meeting that deadline can't depend on millions of website operators each becoming expert cryptographers. It has to be automatic. Until today, preferring post-quantum connections required a manual setting: either you turn them on from Cloudflare’s side, or you have your origin server insist upon them. It was easy to get wrong. But today it’s just … automatic!

TLS 1.3 handshake: guessing the key exchange algorithm

Every secure web connection starts with a TLS handshake, which authenticates the server and derives a shared secret key. Our previous Automatic SSL/TLS blog posts cover that process in detail.

As Cloudflare operates as a reverse proxy, what appears to be a single secure connection is actually two: one between the visitor and Cloudflare, and a second between Cloudflare and the origin server. Each connection operates independently, with its own handshake, identity checks, and encryption keys.

Automatic Key Exchange affects the second connection. When Cloudflare connects to the origin, Cloudflare acts as the TLS client and must begin the handshake. We initiate the connection by sending a ClientHello message containing the hostname and a list of supported key agreement algorithms.

In the happy path, TLS 1.3 can establish a new encrypted connection in just one network round trip (shown on the left in the diagram above). In this case, Cloudflare sends a ClientHello listing its supported key agreement algorithms, along with one or more client keyshares. If the origin accepts that choice, it responds and the handshake completes. This predictive key exchange is an innovation of TLS 1.3, and a large part of why it’s faster than TLS 1.2.

Otherwise, if the origin prefers a different option, it sends a HelloRetryRequest (HRR) and asks Cloudflare to try again (the flow on the right in the diagram above). Cloudflare then sends a second ClientHello, generating a new client keyshare based on the key agreement algorithm specified by the origin. The connection still succeeds, but the retry adds a full network round trip before Cloudflare can fetch content. This is like missing a shortcut in Mario Kart: you still reach the finish line, but you lose the time the shortcut was supposed to save.

Either way, using the client keyshare, the server generates the shared key. The server then returns a server keyshare with which the client can also compute the shared key. This shared key is used to protect the rest of the connection using symmetric cryptography, such as AES.

The cost of the safe guess

For years, our initial client keyshare guess for origin connections using TLS 1.3 was static; we'd always send X25519 while advertising support for other key agreement algorithms. This was a safe strategy because over 95% of origins support X25519, and any origins that didn’t could issue a HelloRetryRequest (HRR) without breaking the connection.

However, X25519 is vulnerable to quantum computers. Since September 2023, we have advertised support of post-quantum key agreement to origins: first as X25519Kyber768Draft00 and today as X25519MLKEM768 (the standardized version of the algorithm). Crucially, advertising support differs from leading with a keyshare in the ClientHello. An X25519MLKEM768 keyshare is 1,216 bytes compared to X25519's 32 bytes, pushing the ClientHello past a single network packet. While the TLS standard allows multi-packet segments, some legacy middleboxes and origin servers can fail when receiving ClientHello messages split across multiple packets. In our previous study, around 0.34% of scanned origins failed to complete the TLS handshake when receiving a post-quantum keyshare first, while the vast majority of origins still relied on classical X25519.

Therefore, to prevent any possible breakage of origin connections, we used HRR as a safety valve. We only advertised post-quantum support, sent a classical X25519 keyshare, and required capable origins to request a post-quantum exchange via retry. For origins that did not support the HRR flow, customers had the option to manually opt into leading with X25519MLKEM768 keyshare. Between 2023 and today, the percentage of origins supporting post-quantum key exchange algorithms grew from 0.5% to 12.8%, and we expect that to keep climbing as hosting stacks upgrade to PQ safe algorithms.

While safe, this default of only upgrading to post-quantum secure connections via retry added unnecessary latency for two reasons:

  • While all modern builds of OpenSSL, BoringSSL, and rustls support X25519MLKEM768, they handle a classical X25519 keyshare differently. Depending on the build, some older builds may accept it by default unless explicitly configured to prioritize the post-quantum secure keyshares, while newer builds will immediately issue an HRR to prioritize post-quantum connections.
  • Over 6% of origins prefer either P-256 or P-384 over X25519, triggering an HRR round trip even for purely classical connections due to our static choice of initial client keyshare.

To eliminate these wasted round trips, we began scanning origin servers to map their exact key agreement capabilities as part of Automatic SSL/TLS. Using these scan results, we automatically tailor our initial keyshare on a per-origin basis: maximizing post-quantum connections without risking site outages, all while making our connections faster for applicable domains.

Extending Automatic SSL/TLS to the post-quantum age

Automatic SSL/TLS now includes Automatic Key Exchange. Across millions of origins, guessing different keyshares carries operational risk, because we have no advance knowledge of how any individual origin is configured. So rather than infer capability, we measure it directly, reusing the scanning pipeline that already powers Automatic SSL/TLS.

For a growing number of origins, this delivers post-quantum key agreement on the very first try at connection setup, without extra round trips and without requiring any manual setup.

This is how it works: 

  1. For each TLS 1.3 capable origin, we run a series of a few lightweight TLS handshakes, each offering exactly one key agreement group: X25519, P-256, P-384, P-521, or X25519MLKEM768. Together these probes tell us the full set of algorithms the origin supports. And because the active scanning happens outside your production traffic path, we confirm that both your origin and the network in between can handle connections with a stronger key agreement before any real traffic depends on it.
  2. A single domain often fronts multiple subdomains that may resolve to different origins with varying capabilities. We evaluate each subdomain independently and weight the results by its actual traffic volume. This ensures a domain-wide preference reflects HTTP traffic volume rather than weighing a dormant subdomain equally with your busiest endpoint. For example, if almost all traffic hits your www and api subdomains, those endpoints would heavily determine the key exchange preference for the entire domain.
  3. From the key agreement groups an origin supports, we then select the strongest candidate using a strict priority order: post-quantum hybrids (X25519MLKEM768) first, falling back to the fastest classical algorithm accepted by the origin (X25519, P-256, P-384, or P-521).
  4. Once we know the optimal key-agreement an origin prefers, we start rolling it out. The new preference goes to a small share of that origin's traffic first, and the system monitors its failure and HelloRetryRequest (HRR) rate while it runs. If retries climb above that origin's baseline, we roll the change back, the same way Automatic SSL/TLS reverts an encryption mode upgrade that may misbehave. At the worst case of rolling back, a bad key-agreement preference costs us an additional round trip latency, not a broken TLS connection for the duration of the rollout phase.
  5. Origin configurations change over time: a customer moves to a new load balancer, a TLS library ships post-quantum support in a routine release, an operator turns off an older key-agreement algorithm support. We rescan every origin daily, so a server that adds post-quantum support, or stops supporting the curve we were using, gets a new preference at the next scan.

For most customers, there is nothing to configure. If your origin speaks TLS 1.3, we will automatically negotiate the strongest key exchange it supports, for instance, if an origin supports X25519MLKEM768, Cloudflare prefers it and can establish post-quantum key agreement without any extra round trip latency.

Configuring Automatic Key Exchange

Automatic Key Exchange is active by default for all existing and new domains, requiring no manual action for most setups. If you want, you can manage these settings independently in the Cloudflare dashboard under SSL/TLS > Overview > Configure > Origin connection & post-quantum encryption.

With the Automatic Key Exchange toggle enabled, Cloudflare scans your origins out-of-band and leads with a dynamically selected keyshare. With it disabled, scanning stops and Cloudflare reverts to a fixed/static default key agreement order.

We have also introduced a new Compliance requirements setting under Automatic Key Exchange. You can filter which key agreements Cloudflare is permitted to use and advertise support for origin connections. When configured, Automatic Key Exchange and all origin-facing traffic strictly observe these rules:

  • Post-quantum hybrid: Restricts negotiation exclusively to hybrid post-quantum key agreements (X25519MLKEM768), removing classical algorithms entirely. All your successful origin TLS 1.3 connections will be guaranteed to be post-quantum secure.
  • Federal Information Processing Standards (FIPS): Restricts negotiation exclusively to FIPS-compliant key agreements.

Selecting both options requires an algorithm that satisfies both criteria simultaneously; if no overlapping key agreement exists, the configuration is rejected. See the Automatic Key Exchange documentation for details.

By selecting these options, you configure your intent rather than specific algorithms. This ensures that as compliance standards evolve or new post-quantum algorithms emerge, your configuration stays up to date automatically. 

However, these requirements are worth approaching carefully. They do not grant an origin new cryptographic capabilities, they only narrow what Cloudflare can negotiate. 

An important note: Enforcing post-quantum hybrid on an origin that lacks X25519MLKEM768 support leaves no mutually supported algorithm, causing all TLS 1.3 connections to fail. Unless you have a strict policy obligation to enforce post-quantum exchange or FIPS compliance across every connection, leave both options unselected and allow Automatic Key Exchange to negotiate the optimal algorithms safely for you.

Making the Internet safer and faster, together

Automatic Key Exchange works for domains whose origins speak TLS 1.3 (as predicting preferred key agreement method is a TLS 1.3-only feature). It’s enabled by default, and our scanning pipeline has already assigned key exchange preferences to well over a million domains while enrollment continues across the remaining network.

From that initial cohort, we found that roughly 64% of them stayed on the classical X25519 as their preference, so nothing about their connections changed. Around 33% of them now have their preference set to X25519MLKEM768, which causes traffic to those origins protected from harvest-now, decrypt-later quantum attacks in a single round trip. The remaining 3% selected a different classical curve preferred by their origin, such as P-384, P-256, or P-521.

Approximately 9,000 domains each day have their key agreement preference set to a key agreement method other than X25519. Nearly all of these move directly to preferring post-quantum key exchange, while the remainder adopt other classical curves better supported by their origin’s TLS configuration.

As we mentioned earlier, prior to Automatic Key Exchange, almost every post-quantum origin handshake required a HelloRetryRequest (HRR) because our static initial guess defaulted to classical X25519. The result was that post-quantum connections paid a mandatory second round trip before completing the TLS handshake.

With the rollout underway, that latency penalty is virtually gone for almost all post-quantum capable origins: 99.2% of post-quantum TLS 1.3 connections of the currently scanned cohort of origins now complete in a single round trip. Beyond removing the extra round trip, we see that across that cohort, post-quantum origin traffic keeps growing from roughly 25 billion connections to 45 billion per day. A significant part of that growth has come from Automatic Key Exchange upgrading classical connections to a post-quantum preference for scanned origins.

Many origins support multiple key agreement algorithms without preferring one over another. For example, an origin that supports post-quantum key agreement may still accept a classical (X25519) key share without rejecting it or issuing an HRR. Passive observation, therefore, cannot reveal the origin’s full capabilities. Active probing allowed Automatic Key Exchange to uncover thousands of origins whose post-quantum support never appeared in their origin traffic.

Once our scanner discovered such origins, and updated their client keyshare preference, post-quantum connections quickly accounted for the vast majority of traffic to these origins. Other classical key agreement algorithms represent a much smaller share for these upgraded domains, primarily driven by multi-origin setups with a mix of post-quantum and classical-only backends.
Automatic Key Exchange does more than just drive post-quantum adoption. It also helps pair origins with their preferred classical curve (other than X25519), reducing overall HRR rates across all scanned origins.

Before we enabled Automatic Key Exchange, roughly 52% of origin connections for the scanned domains required an HRR. That rate fell to just 3.7%. Avoiding an HRR removes an entire round trip from TLS connection setup, reducing p90 latency more than 150 ms for the scanned origins. This particularly benefits dynamic requests and CDN cache misses that may require a new TLS 1.3 connection to the origin, ultimately reducing latency for eyeballs. Requests sent over existing keep-alive connections do not require a new handshake and are therefore unaffected.

Is the server post-quantum capable?

There are a number of different tools to use to find out if a server supports post-quantum key agreement. We offer one of these tools via Cloudflare Radar. Enter the hostname or IP addresses of your server, and we will check if it supports post-quantum TLS key exchange. Note that if you enter a hostname proxied by Cloudflare, Radar will check the connection to Cloudflare rather than your origin server behind it.

Beyond verifying algorithm support, we have added the ability in the tool to check for post-quantum TLS implementation bugs. If the results come back negative, it will also try to characterize the reason for the failure. Failures often stem from legacy middleboxes, firewalls, or server buffers dropping multi-packet payloads or failing to reassemble a ClientHello split across TCP segments. Other times the origin gives up on an unrecognized key share instead of sending a HelloRetryRequest as TLS 1.3 requires, or sends one and then cannot finish the handshake.

Radar gives you a clear picture of whether the network path handles post-quantum traffic cleanly. Automatic Key Exchange will not switch a domain whose origin fails these checks, so clearing them is what lets the upgrade happen.

What if your origin doesn't support post-quantum key agreement yet?

Even if your origin does not yet support post-quantum encryption today, the good news is that enabling Auto Key Exchange will still be beneficial. Automatic Key Exchange finds what your origin supports. If X25519MLKEM768 is unavailable, Cloudflare continues using a compatible classical key agreement and can still avoid unnecessary HelloRetryRequest round trips by learning which one your origin prefers.

However, Automatic Key Exchange can only prefer post-quantum connections when your origin server already supports the key agreement algorithm. Today, we see over 12% of individual origins across our network support post-quantum encryption. Post-quantum secure algorithms support in TLS server implementations is increasing as recent versions of BoringSSL, OpenSSL, and rustls include support. The enterprise origin stacks, cloud load balancers, and embedded TLS terminators are upgrading on their own timelines.

If you want to add post-quantum protection capability for your domain’s origin-facing connections, you have two options:

  • You can upgrade your TLS endpoint. Many current frameworks and TLS libraries enable X25519MLKEM768 by default. However, if you previously configured allowed curves manually for your server’s TLS configuration, those legacy settings might override the new defaults. It is important to audit every device terminating or inspecting TLS—including load balancers, WAF appliances, and other middleboxes—to ensure X25519MLKEM768 is enabled on everything that sits between your origin and Cloudflare. If you’re on a managed hosting service, ask your provider whether it supports X25519MLKEM768 (many do).

See Post-quantum cryptography between Cloudflare and your origin for supported software, configuration examples, and verification steps.

What's next

We’ve been building Automatic SSL/TLS in public since 2024. Automatic Key Exchange is the second step in a longer arc, not the last. We’ve been public about what’s on the roadmap since then and will continue to provide updates as we ship. A few specific things we’re working on:

Per-origin preference granularity 

Today, Automatic SSL/TLS makes its decisions at the domain level. One origin server's behavior can hold the whole domain back. We're working on a per-subdomain/per origin granularity so that key agreement (and SSL/TLS encryption modes) can vary across the multiple origins that serve a single domain.

On-demand scans

If you've just upgraded your origin's TLS stack, you shouldn't have to wait for the next scheduled scan by Automatic SSL/TLS. Originally, we wanted to scan enough to keep up with changes on the origin, but not too much so as to burden origins who ultimately return the same security information. We're building an option to trigger an on-demand rescan from the dashboard or API, so post origin upgrade you can move to the better key agreement immediately rather than waiting for our system to catch up.

Beyond triggering instant updates, this on-demand scan will live directly in your Cloudflare dashboard as a diagnostic tool. It will let you test your own origin server's behavior on demand and see exactly which key agreements it can successfully negotiate, and characterize the reasons for any failures (similar to the external Cloudflare Radar scanning tool).

Automatic post-quantum origin authentication  

Post-quantum key agreement keeps today's traffic from being decrypted by a future quantum computer. It does nothing about an attacker who uses one to forge a certificate and impersonate your origin. Closing that gap takes post-quantum authentication, which came to origin connections earlier this year when Authenticated Origin Pulls and Custom Origin Trust Store gained support for ML-DSA certificates.

There is an important issue to deal with here: downgrades. Imagine your origin server supports both a classical RSA/ECDSA certificate and a new post-quantum ML-DSA certificate so legacy clients don't break. On Q-Day, an active adversary sitting between Cloudflare and your origin could intercept the TLS handshake and silently drop the post-quantum offer. Cloudflare, seeing only a classical response, would fall back to validating the legacy RSA/ECDSA certificate, which the attacker can forge using a quantum computer.

Preventing this downgrade in the broader WebPKI is complicated. One proposed path involves Certificate Authorities (CAs) placing a post-quantum signature on a classical certificate to prove that a legacy server truly doesn't support PQ yet. While this is a likely direction for the public web, it will take some time and coordination. What’s quicker (if possible!) is to stop trusting classical certificates altogether.

And for origin connections, we can! We plan to extend Automatic SSL/TLS scanning to detect origin support for post-quantum authentication (ML-DSA certificates; and in future Merkle Tree Certificates). Once our scanner identifies such an origin, Cloudflare can automatically disable classical fallback for customers who want strict post-quantum protection, eliminating downgrade risks without disrupting un-upgraded endpoints.

Check it out

At Cloudflare, we believe that strong security on the Internet should be free, automatic, and on by default. Universal SSL made encryption-by-default real for the browser-to-Cloudflare connection. Automatic SSL/TLS is doing the same for the Cloudflare-to-origin connections, and now extends that work to post-quantum key agreement.

If you want to see what your origin encryption level looks like today, check the SSL/TLS section of your dashboard. If you want to verify your origin's post-quantum readiness directly, Cloudflare Radar will tell you if you need to update your server stacks. And if your origin already supports post-quantum, Automatic Key Exchange will tell Cloudflare so that we will connect to your origin faster and more securely.
CVE-2026-86206, CVE-2026-86207: N-able N-central Authentication Bypass (FIXED)

Post Syndicated from Stephen Fewer original https://www.rapid7.com/blog/post/ve-cve-2026-86206-cve-2026-86207-n-able-n-central-authentication-bypass-fixed

Overview

While conducting research into a recent N-able N-central authentication bypass vulnerability (CVE-2026-18577), Rapid7 Labs discovered two new vulnerabilities affecting the latest version of N-central. When chained together, these two vulnerabilities allow a remote unauthenticated attacker to bypass authentication and create a new attacker-controlled System administrator account on an affected server.

CVE ID

Description

CWE

CVSSv4

CVE-2026-86206

Semicolon/Forwarded access-control bypass

CWE-791

6.9 (Medium)

CVE-2026-86207

UserTwoFactorLogin authentication bypass

CWE-305

7.7 (High)

Both CVE-2026-86206 and CVE-2026-86207 have been patched by the vendor via N-central 2026.3 Hotfix 3.

Product description

N-able N-central is an enterprise-grade Remote Monitoring and Management (RMM) platform designed for Managed Service Providers (MSPs) and IT departments to monitor, manage, and secure complex, large-scale networks from a centralized dashboard.

Credit

These vulnerabilities were discovered by Stephen Fewer, Senior Principal Security Researcher at Rapid7, and are being disclosed in accordance with Rapid7’s vulnerability disclosure policy.

Technical analysis

CVE-2026-86206

N-central exposes its management interface (TCP 8443 by default) through Envoy, an edge proxy. Envoy passes accepted requests to Jetty, the Java web server that hosts N-central’s application. The application gives requests from the loopback address (i.e. 127.0.0.1) more access than requests from a remote system. This design depends on Envoy, Jetty, and the N-central access filter all agreeing on which application path the client requested and whether the client is really local. The following request can make them disagree about both of these things:

POST /dms;/services/ServerUI HTTP/1.1
Forwarded: for="127.0.0.\1"
Content-Type: text/xml; charset=utf-8
SOAPAction: ""

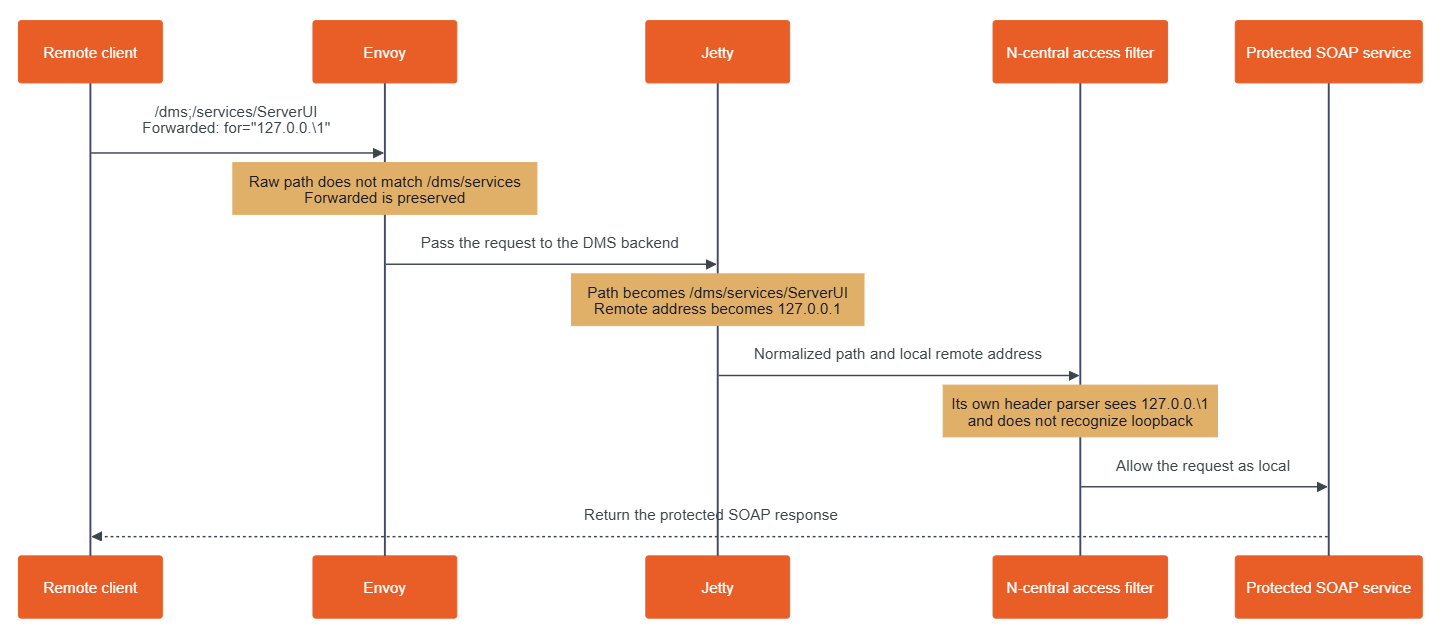
The semicolon in the URI and backslash in the Forwarded value introduce a discrepancy when processing the request that leads to an access control bypass. Looking at Figure 1 below, we can see an overview of how these two values are processed during an incoming malicious request.

nable_cvd_blog.png

Figure 1: Processing a malicious request.

The semicolon gets the request past Envoy

The Envoy proxy rules come from the n-central-proxy-4.5.6-5 package. In /etc/opt/envoy/lds_intermediate.yaml, shown below (and edited for brevity), the management listener returns HTTP 403 for paths beginning with /dms/services or /internal/dms. A final catch-all rule sends other paths to the DMS application.

  # /etc/opt/envoy/lds_intermediate.yaml:953
  - match:
      prefix: /internal/dms
    # response-header boilerplate omitted
    direct_response:
      status: 403
      body:
        inline_string: Forbidden. No API access on the UI port.
  # ...
  - match:
      prefix: /dms/services
    # response-header boilerplate omitted
    direct_response:
      status: 403
      body:
        inline_string: Forbidden. No API access on the UI port.
 # ...
 # /etc/opt/envoy/lds_intermediate.yaml:1301
 # A final catch-all rule...
  - match:
      prefix: /
    route:
      cluster: dms
      timeout:
        seconds: 300

Envoy compares those prefixes with the path it received. The path /dms;/services/ServerUI does not begin with /dms/services, because the next character after /dms is a semicolon. It therefore reaches the catch-all route, passing the request from Envoy to Jetty.

Jetty interprets the path differently. The shipped jetty-http-9.4.56.v20240826.jar contains org.eclipse.jetty.http.HttpURI, and org.eclipse.jetty.util.URIUtil. Together, these classes treat text beginning with a semicolon as a path parameter and remove it when producing the decoded path used for servlet dispatch. As a result, Jetty turns /dms;/services/ServerUI into /dms/services/ServerUI. That decoded path then matches the Axis SOAP servlet mapping in /opt/nable/webapps/ROOT/WEB-INF/web.xml

<!-- /opt/nable/webapps/ROOT/WEB-INF/web.xml -->
<!-- ...snip... -->

   <servlet>
        <servlet-name>DMSServlet</servlet-name>
        <servlet-class>org.apache.axis.transport.http.AxisServlet</servlet-class>
    </servlet>
    <servlet-mapping>
        <servlet-name>DMSServlet</servlet-name>
        <url-pattern>/dms/services/*</url-pattern>
        <url-pattern>/internal/dms/services/*</url-pattern>
    </servlet-mapping>

    <servlet>
        <display-name>CXF Servlet</display-name>
        <servlet-name>CXFServlet</servlet-name>
        <servlet-class>org.apache.cxf.transport.servlet.CXFServlet</servlet-class>
        <load-on-startup>2</load-on-startup>
    </servlet>
    <servlet-mapping>
        <servlet-name>CXFServlet</servlet-name>
        <url-pattern>/dms2/services2/*</url-pattern>
        <url-pattern>/internal/dms/services2/*</url-pattern>
    </servlet-mapping>

Similarly, the same technique can be used to target the SOAP service via /internal;/dms/services2/ServerUI2. Jetty decodes it to /internal/dms/services2/ServerUI2, which matches the CXF SOAP servlet mapping. A single semicolon is sufficient to create the routing disagreement.

Reaching these servlet mappings puts the request at the protected SOAP interfaces that an exploit can leverage to establish an application session and later manage privileged objects, but the semicolon trick alone does not authorize the request. Without the crafted Forwarded header, Jetty retains the client’s real remote address and N-central’s ServletPathFilter denies access. Conversely, the header trick alone cannot help a request to the ordinary /dms/services/ServerUI or /internal/dms/services2/ServerUI2 path: Envoy returns HTTP 403 without forwarding that request to Jetty. 

As such, an exploit needs both discrepancies; the semicolon to pass Envoy’s path check and the header to pass N-central’s local-request check.

The header makes the remote client look local

The Forwarded header tells an application about the original client behind a proxy. In a malicious request, the for value is quoted and contains a quoted-pair (\1):

Forwarded: for="127.0.0.\1"

Under the HTTP quoted-string grammar, the backslash escapes the following character. Jetty’s ForwardedRequestCustomizer, from jetty-server-9.4.56.v20240826.jar, applies that rule. It removes the backslash, reads the value as 127.0.0.1, and exposes that value to N-central as the request’s remote address.

N-central then parses the original header a second time. Its parser is in com.nable.util.LocalHostUtils, from /opt/nable/webapps/ROOT/WEB-INF/lib/dmsservice-11.0.1-SNAPSHOT.jar. This parser removes the surrounding quotes but does not remove the backslash. It therefore checks 127.0.0.\1.

That string is not a valid IP address. LocalHostUtils.xffCheck() rejects an invalid value found in X-Forwarded-For, but its Forwarded branch rejects only values that it successfully recognizes as loopback. The below (abridged) decompilation shows the relevant branch:

// dmsservice-11.0.1-SNAPSHOT.jar
// com.nable.util.LocalHostUtils.xffCheck()

List<String> forwardedAddresses =
    LocalHostUtils.getForAddressesFromForwardedHeaders(httpRequest);

for (String addr : forwardedAddresses) {
    if (!LocalHostUtils.isLoopbackAddress(addr.trim())) continue; // <--- [1]
    // log the rejected loopback address
    return false; // <--- [2]
}
return true; // <--- [3]

When given the header value 127.0.0.\1, the isLoopbackAddress() call (at [1]) returns false (at [2]) because the value is invalid. The loop therefore continues and xffCheck() returns true (at [3]). In other words, an invalid Forwarded header value causes xffCheck to fail open. The final decision occurs in com.nable.server.ServletPathFilter, shown below.

// dmsservice-11.0.1-SNAPSHOT.jar
// com.nable.server.ServletPathFilter.isAllowedRequest()

boolean isAllowedRequest(HttpServletRequest httpRequest) {
    if (!LocalHostUtils.xffCheck(httpRequest)) { // <--- [4]
        return false;
    }
    if (LocalHostUtils.isLocalhost(httpRequest)) { // <--- [5]
        return true; // <--- [6]
    }
    String path = this.removeTrailingSlashes(httpRequest.getRequestURI());
    return this.pathFilterService != null
        && this.pathFilterService.isPathAllowed(path);
}

The first check asks whether a forwarding header is trying to claim a loopback address (at [4]). N-central’s parser sees the invalid value 127.0.0.\1, does not recognize it as loopback, and allows it. The second check asks whether Jetty’s remote address is local (at [5]). Jetty has already converted the same header value to 127.0.0.1, so this check succeeds. The filter returns true (at [6]) before consulting the normal remote-path allowlist.

CVE-2026-86207

By leveraging CVE-2026-86206 to reach the protected URI /dms/services/ServerUI, a SessionID returned by the Session.Hello SOAP operation (See the prior work by Horizon3 on leveraging the legacy SOAP API) can be generated. However, this SessionID is only a pre-login session. It proves that the request reached the local-only SOAP API via the access control bypass, but it does not yet identify an authenticated user. A separate authentication bypass vulnerability, in how legacy two-factor authentication operates, allows a pre-login session to become an authenticated session.

The method com.nable.server.ui.UserTwoFactorLogin, from dmsservice-11.0.1-SNAPSHOT.jar (shown below), binds a requested user ID (e.g. the builtin N-able Administrator account’s well known ID 1) to the session (at [1]) before it attempts legacy two-factor authentication (at [2]) . A normal authentication rejection removes that binding (at [4]), but if an exception occurs, this binding is left in place (at [3]).

// dmsservice-11.0.1-SNAPSHOT.jar
// com.nable.server.ui.UserTwoFactorLogin

   public final String twoFactorLogin(int sessionID, int userID, String password) throws RemoteException {
        String response = null;
        try {
            this.updateSession(sessionID, userID); // <--- [1]
            T_User user = this.getUser(userID);
            response = this.authenticate(user, password); // <--- [2]
            Trace.info((Object)this, (String)("2FA authentication response for user '" + user.getUsername() + "': " + response));
            if (response != null && "ACCESS_OK".equals(response)) {
                String audit = "TWO FACTOR LOGIN SUCCESSFUL: UserID [" + userID + "] successfully logged in.";
                this.addSessionAuditEntry(sessionID, audit);
            } else {
                String audit = "TWO FACTOR LOGIN FAILED: UserID [" + userID + "] attempted to login with invalid PIN.";
                this.addSessionAuditEntry(sessionID, audit);
                this.makeSessionInvalid(sessionID); // <--- [4]
            }
        }
        catch (RemoteException re) {
            throw re; // <--- [3]
        }
        catch (Exception ex) {
            throw DMSError.getFault((String)CommonError.GENERIC_ERROR.getCodeAsString(), (String)ex.toString(), (Throwable)ex); // <--- [3]
        }
        return response;
    }

N-central supports two distinct second-factor systems: legacy, profile-based authentication using an external AuthAnvil or RSA SecurID server, and native time-based one-time password (TOTP) “Two-Step Verification” using an authenticator application. Despite overlapping 2FA/MFA terminology in N-able’s documentation, com.nable.server.ui.UserTwoFactorLogin implements the former profile-based mechanism; it does not enforce the user’s native TOTP setting.

In a default installation, legacy two-factor processing raises an exception for several builtin identities used by N-central, as each of these identities lack a single legacy AuthAnvil or RSA 2FA profile association required by UserTwoFactorLogin. Specifically the following built-in identities can be leveraged via their known ID numbers.

  • User ID 1 (N-able Administrator)

  • User ID 50 (Product Administrator)

  • User ID 51 (N-able Support)

By creating a new pre-login session for any one of the above IDs, a SOAP call to User.TwoFactorLogin with a dummy password will achieve the authentication bypass, converting the pre-login session to a privileged SOAP session for that user. By using additional calls to the ServerUI2 SOAP endpoint, a new attacker-controlled System user account can be created.

Remediation

The vendor-supplied release of N-central 2026.3 Hotfix 3 (version 2026.3.1.13) remediates both CVE-2026-86206 and CVE-2026-86207. All versions of N-central prior to 2026.3.1.13 are vulnerable. Customers running affected on-premise N-central environments are urged to apply the latest update on an urgent basis, outside of normal patching cycles.

Customers using hosted N-central environments do not need to take action as the vendor has applied the needed updates.

For the latest remediation guidance, please see the vendor release notes and the vendor disclosure blog.

Rapid7 customers

Exposure Command, InsightVM, and Nexpose

Exposure Command, InsightVM and Nexpose customers will be able to assess their exposure to both CVE-2026-86206 and CVE-2026-86207, with authenticated vulnerability checks expected to be available in the September 8 content release. 

Disclosure timeline

  • August 27, 2026: Rapid7 makes initial outreach to N-able who respond the same day.

  • August 28, 2026: Rapid7 provides a detailed technical analysis and exploit script to N-able, along with a proposed timeline for a coordinated disclosure.

  • September 5, 2026: N-able release N-central 2026.3 HF3 which fixes two of the vulnerabilities (CVE-2026-86206, CVE-2026-86207) reported by Rapid7.

  • September 7, 2026: Rapid7 contacts N-able requesting clarity on several issues. N-able responds the same day with requested information.

  • September 8, 2026: This disclosure for CVE-2026-86206 and CVE-2026-86207.

Stealing AI Reasoning Traces

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/stealing-ai-reasoning-traces.html

Interesting research: “Stealing Reasoning Traces from Proprietary LLM APIs“:

Abstract: Leading large language model providers now conceal their models’ step-by-step reasoning, or chain-of-thought, to protect intellectual property and limit information leakage. Rather than storing these traces server-side, providers return them to the client as blocks of encrypted text, which the client passes back with each subsequent request. Building on prior research, we identify an architectural vulnerability: these encrypted blocks are fully compatible and interchangeable across different sessions, users, and models within a provider’s ecosystem. We exploit this compatibility to develop a scalable decryption jailbreak. By injecting an encrypted reasoning trace from a given model into a weaker, and less safeguarded model from the same provider, we force it to decode and output the trace verbatim in plaintext, without ever jailbreaking the more capable model directly. This vulnerability enables four distinct attack vectors. First, it circumvents anti-distillation mechanisms, allowing adversaries to extract a proprietary model’s reasoning, as we demonstrate across Anthropic, OpenAI, and Google. Second, it allows for large-scale private data extraction. Developers frequently share session logs publicly, unaware of contents of the encrypted blocks. By decoding 315,320 reasoning blocks scraped from public repositories, we recovered 367 Personally Identifiable Information (PII) artifacts and 182 credentials. Third, it inadvertently reveals hazardous information hidden within the reasoning process, even in cases where the model’s final, visible output safely rejects a malicious request. Fourth, attackers can leverage this flaw to execute invisible prompt injections, embedding malicious payloads entirely within encrypted blocks to poison public agentic rollouts. Following responsible disclosure, we propose concrete cryptographic and system-level mitigations to secure client-side reasoning.

Join the UK Bebras Challenge 2026

Post Syndicated from Andrew Csizmadia original https://www.raspberrypi.org/blog/join-the-uk-bebras-challenge-2026/

The UK Bebras Challenge, the nation’s largest computing challenge, is back!

Last year, more than 526,000 students from across the UK took part, tackling fun and thought-provoking puzzles that introduce key ideas in computational thinking with no extra preparation needed.

Read on to learn how your school can get involved.

What is the UK Bebras Challenge?

The UK Bebras Challenge is a free-to-enter annual challenge that is designed to spark interest in both computational thinking and computer science among students aged 6 to 19. The 45-minute challenge is accessible to everyone, offering age-appropriate but challenging interactive tasks for students at different levels, including a tailored version for secondary students with severe sight impairments.

The tasks are designed to give every student the opportunity to showcase their potential and all participating students receive a certificate. There are also certificates based on performance within school and gold certificates based on national boundaries. With self-marking tasks and no text-based programming required, it’s easy to have your school participate in the UK Bebras Challenge.

“The UK Bebras challenge provides an engaging way for students to apply their problem-solving skills in a fun, competitive environment. It complements our coding curriculum, encouraging critical thinking and enhancing computational thinking,” – Jonathan Phillips from Hereford Cathedral School

A new way to celebrate your achievements

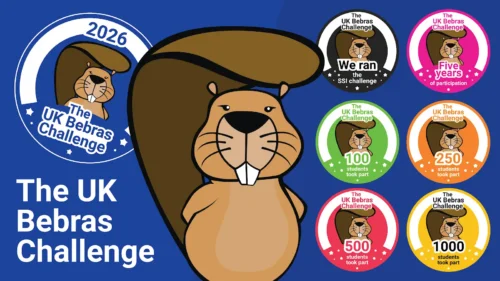
A cartoon beaver next to some digital badges for the Bebras Challenge.

Every student who takes part in the UK Bebras Challenge gets a certificate. This year, we’ve come up with a new way to celebrate schools too. Every school who takes part will now get a digital badge and can earn others for reaching participation milestones.

The badges categories are:

  • 2026 UK Bebras Challenge participants
  • 100 students take part
  • 250 students
  • 500 students
  • 1,000+ students
  • 5 years running the challenge (starting this year)
  • Running the Severe Sight Impairment (SSI) challenge

With the exception of the ‘5 years’ badge, the numbers aren’t cumulative year-on-year and reset for each new challenge year. Claiming the badges is easy: Once the results are processed, we’ll email you a link where you can download your badge and display it wherever you want.

Feel free to brag about your new badges online. It might encourage other schools to take part next year 😀

Go deeper with Ada Computer Science

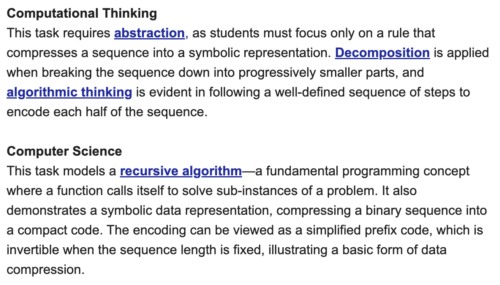
Text that reads: "Computational thinking: this task requires abstraction, as students must focus only on a rule that compresses a sequence into  a symbolic representation. Decomposition is applied when breaking the sequence down into progressively smaller parts, and algorithmic thinking is evident in following a well-defined sequence of steps to encode each half of the sequence. Computer science: this task models a recursive algorithm - a fundamental programming concept where a function calls itself to solve sub-instances of a problem. It also demonstrated a symbolic data representation, compressing a binary sequence into a compact code. The encoding can be viewed as a simplified prefix code, which is invertible when the sequence length is fixed, illustrating a basic form of data compression."
An example of the related computing concepts you’ll now see under every challenge puzzle.

Each Bebras task’s background section is now linked to a related topic on the Ada Computer Science platform. Following the live challenge, teachers and students can explore ithe detailed explanation of the computer science concept behind each Bebras task, along with the computational thinking skills students may use to solve that task.

“We have thoroughly enjoyed delivering the UK Bebras Challenge at our school. It has been an invaluable resource and by participating in this exciting event, our students have been introduced to the world of computational thinking in a fun and engaging way. The challenges are designed to push students to think critically and creatively, developing essential problem-solving skills that are applicable both inside and outside of the classroom.” – Sharon Pendreigh from Brownedge St Mary’s Catholic High School

How do I get my school involved?

If you are either a UK school or teach a UK-based curriculum, then visit the UK Bebras website for more information and to register your school.

Once you’ve registered, you’ll get access to the entire UK Bebras set of questions from previous years, allowing you to create custom quizzes for your students to tackle at any time throughout the year. These quizzes are self-marking, and you can download your students’ results to keep track of their progress. The questions are perfect for enrichment activities, end-of-term quizzes, lesson starters, and even full lessons to develop computational thinking skills and promote computing concepts.

Register for free at bebras.uk/admin.

Have a go at one of our puzzles

Here’s a question we ran in 2018 for the Juniors group (ages 10 to 12). Can you solve it?

Park walk

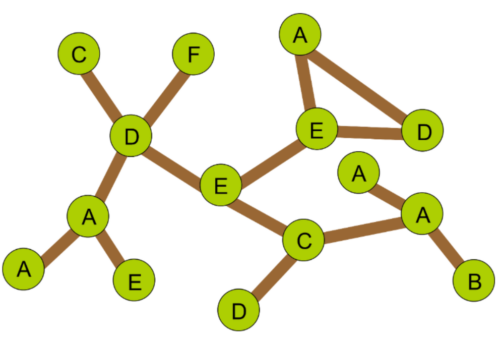
This is the map of a park:

A diagram with lines connecting to circles each containing a letter of the alphabet.

The green circles with letters represent the trees and the brown lines are paths. Note that some letters are used to label more than one tree. Walking from tree F to tree B can be described as F D E C A B.

Last Sunday two families walked in the park.

The Wilde family’s walk was B A A A C E D E E D A.

The Gilde family’s walk was F D C D A E A D E D A.

Both families started their walks at the same time.

Walking from one tree to another tree, down one path takes the same amount of time.

Question:

How many times did the two families meet at a tree?

A screenshot of the answer options : "Once, Twice, Three times, They never met any of the trees".

Answer

They never met at any of the trees.

Explanation

Computer scientists often use graphs (and then they speak about vertices and edges instead of trees and paths connecting them).

Another interesting point about this task is the representation of the walks in the park. Despite the fact that some of the trees (vertices) are marked by the same letter, the walks that start from B or F can be unambiguously described by the sequence of letters along the walk. It means that one sequence of letters describes only one walk. It is because the neighbours of each tree (neighbours of tree X are the trees that are directly connected to X by a path) are always labeled with different letters. So if we know where we are at some moment of the walk and we see the next letter in the walk’s representation then there is no doubt which tree we should visit next.

This Bebras task was developed by the Bebras team in South Korea and refined by members of the international Bebras community.

In 1936, a Hungarian mathematician called Dénes Kőnig wrote the first ever textbook on graph theory. Today, graph theory is fundamental to computer science and in particular networking, operation research and data structures.

Did you get it right?

The post Join the UK Bebras Challenge 2026 appeared first on Raspberry Pi Foundation.

Canonical Evolution of Enterprise Open Source RISC-V at Hot Chips 2026

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/canonical-evolution-of-enterprise-open-source-risc-v-at-hot-chips-2026/

Canonical gave a talk about the state of enterprise open source with RISC-V at Hot Chips 2026 as we move toward broader adoption

The post Canonical Evolution of Enterprise Open Source RISC-V at Hot Chips 2026 appeared first on ServeTheHome.

[$] CERN’s migration path from CentOS Linux to Debian

Post Syndicated from jzb original https://lwn.net/Articles/1092512/

The European Laboratory for Particle Physics, usually just called CERN, is not only the birthplace of
the World Wide Web
, it is home to the Large Hadron
Collider
(LHC), the world’s largest and highest-energy particle
accelerator
. As such, its computing environment is both truly unique and of
great interest to people outside of CERN who hope to find lessons applicable to
their own computing needs. The upcoming migration of some of CERN’s systems from
CentOS Linux to Debian, which was the topic of a talk at the recent MiniDebConf Winterthur 2026,
is of particular interest.

[$] Fixing the TCMalloc regression with RSEQ operations

Post Syndicated from corbet original https://lwn.net/Articles/1092555/

The restartable sequences feature is one of
the stranger corners of the kernel’s user-space interface; it provides a
way for user space to carry out simple lockless operations and be informed
if it is preempted over the course of an operation (and must, thus,
restart). Work merged in the 6.19 release to improve the performance of restartable
sequences
broke the TCMalloc allocator,
which was relying on an undocumented (and unintended) kernel behavior.
Now, Olivier Dion is proposing an
addition
to the restartable-sequences API that will bring TCMalloc back
into the fold; it does not make the restartable-sequences API any less
strange, though.

AWS Weekly Roundup: Claude Fable 5.1 on AWS, Amazon Linux 2027 preview, AWS Certified AI Business Strategist, and more (September 7, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-fable-5-1-on-aws-amazon-linux-2027-preview-aws-certified-ai-business-strategist-and-more-september-7-2026/

Last week, Claude Fable 5.1 became available on AWS. According to Anthropic, Claude Fable 5.1 delivers frontier intelligence for ambitious tasks across coding, scientific research, and enterprise workflows. Claude Fable 5.1 is built for long-running, high-stakes work that runs for hours and spans many applications. It can own more of a software project on its own, handling features across an entire codebase, code review, and performance work over extended sessions.

Anthropic has designated Fable 5.1 a Covered Model, a category of Claude models that carry additional data retention, safety review, and access policies wherever they’re offered. Claude Fable 5.1 is subject to data retention for up to 30 days and human review by Amazon personnel, with a new aws_review data retention mode. In this mode, AWS retains your prompts and outputs for human safety review within the AWS boundary. The provider_data_share mode is legacy, and Amazon Bedrock does not share your data with the model provider. In addition, Enterprise Frontier Safeguards (EFS), built in partnership between AWS and Anthropic, will let eligible customers use Covered Models while keeping their data in a cloud environment they control.

You have two ways to access Claude Fable 5.1: Amazon Bedrock and Claude Platform on AWS. To learn more, see the Claude Fable 5.1 model card on Amazon Bedrock and Claude Platform on AWS.

Last week’s launches
Here are some launches that got my attention:

  • Amazon Linux 2027 (AL2027) in public preview: AL2027 is the next version of the Amazon Linux operating system. It runs on kernel 7.1+, purpose-built for cloud-native workloads on AWS with performance, scale, and security in mind. Built on AL2023’s baseline, AL2027 is designed for customers who need a secure, stable, and AWS-native operating system running web applications, databases, containerized microservices, AI/ML workloads, and large-scale infrastructure.
  • Amazon EC2 R9g and R9gd memory-optimized instances: These instances are powered by AWS Graviton5 processors, delivering the best price performance for memory-intensive workloads running on Amazon EC2. R9g and R9gd instances deliver up to 25% better compute performance compared to AWS Graviton4-based R8g and R8gd instances. They are up to 30% faster for databases, up to 35% faster for web applications, and up to 35% faster for machine learning. To learn more, read Daniel’s blog post.
  • AWS Lambda SnapStart for container image functions: Lambda SnapStart is an opt-in capability that makes it easier for you to build highly responsive and scalable applications without provisioning resources or implementing complex performance optimizations. Previously, SnapStart was only supported for managed runtimes (Python, .NET, and Java). You can now use SnapStart for container images to reduce startup times from several seconds to as low as sub-second for latency-sensitive workloads such as ML inference and interactive APIs.
  • AWS Agent Registry now generally available: AWS Agent Registry provides a private, governed catalog and discovery layer for agents, tools, skills, MCP servers, and custom resources within your organization. In addition to the capabilities launched in preview (manual and URL-based record creation, approval workflows, semantic and keyword search, and AWS CloudTrail audit trails), Registry now adds new enterprise features. To learn more, visit the AI Blog post.
  • Amazon Redshift now supports Apache Iceberg v3 tables: You can read from and write to Apache Iceberg v3 tables in your data lake of Amazon Redshift. With this launch, Amazon Redshift introduces support for default column values, row lineage, and deletion vectors. Amazon Redshift’s Graviton based provisioned and serverless clusters support the new v3 format. To learn more, visit Apache Iceberg v3 features in Redshift.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional projects and news items you may find interesting:

  • AWS named a Leader in the 2026 Gartner Magic Quadrant for Strategic Cloud Platform Services: For the 16th consecutive year, Gartner has recognized AWS as a Leader in the 2026 Gartner Magic Quadrant for Strategic Cloud Platform Services, and once again placed AWS highest on the Ability to Execute axis. We believe this recognition reflects our commitment to delivering the broadest and deepest set of cloud capabilities from infrastructure and AI to security and operations, so you can build, innovate, and scale with confidence.
  • AWS Certified AI Business Strategist: This new certification targets professionals who evaluate, champion, and scale AI initiatives in their organizations: line-of-business leaders driving adoption across their teams, sales professionals articulating AI value to customers, consultants guiding client strategy from experimentation through production, program managers aligning AI investments to business outcomes. Beta exam registration opened September 1, 2026, with exam delivery beginning September 29.
  • Agentic Security: Detection and Response at Machine Speed: We believe security should evolve ahead of AI adoption, not behind it. That belief drove our team to collaborate with the SANS Institute on a new chapter in the 2026 Cloud Security Exchange eBook, where we lay out a practical framework for securing agentic workloads at enterprise scale. Our chapter goes deeper on securing agentic workloads, with specific architectural patterns, implementation guidance, and frameworks for security teams at every stage of agentic AI maturity, whether you’re evaluating, piloting, or operating at scale.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events including AWS re:Invent, AWS Summits, and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That is all for this week. Check back next Monday for another Weekly Roundup!

Channy

Security updates for Monday

Post Syndicated from jzb original https://lwn.net/Articles/1092911/

Security updates have been issued by AlmaLinux (buildah, freerdp, gegl04, go-fdo-client, grafana, grafana-pcp, kernel, and pipewire), Debian (aom, chromium, libde265, libssh2, thunderbird, and tryton-server), Fedora (chromium, composer, cosmic-greeter, gegl04, greetd, ibus-table, jss, libheif, lightdm, lxdm, memcached, perl-DBD-Pg, plasma-login-manager, rust-webbrowser, sddm, selinux-policy, slitherer, and tkimg), Mageia (expat, mingw-expat, mbedtls, microcode, python-linkify-it-py, and tomcat), Oracle (buildah, container-tools:ol8, dbus-broker, freerdp, go-toolset:ol8, grafana-pcp, kernel, kernel-uek, nodejs24, php, and pipewire), Slackware (libpcap, libxml2, mozilla-firefox, mozilla-thunderbird, and util-linux), SUSE (bson-devel, busybox, bzip2, c-ares, cpio, cups-filters, dracut, ffmpeg-7, ffmpeg-8, file-roller, firefox, firefox-esr, glances-common, grafana, hauler, helm, helm3, java-17-openjdk, java-21-openjdk, lcms2, libcupsfilters, libheif, libmsgpack-c2, libsoup, libsoup2, libusb-1_0, libvirt, LibVNCServer, mcphost, ollama, opencode, openssl-1_1, openssl-3, php-composer2, podman, postgresql15, postgresql17, postgresql18, python, python-aiohttp, python-h2, python-sqlparse, python310, rpcbind, sssd, thunderbird, trivy, ucode-intel, and webkit2gtk3), and Ubuntu (linux, linux-aws, linux-aws-7.0, linux-gcp, linux-gke, linux-hwe-7.0, linux-realtime, linux, linux-aws, linux-fips, linux-kvm, linux-lts-xenial, linux, linux-fips, linux-gcp, linux-gcp-fips, linux-gke, linux-gkeop, linux-nvidia, linux-nvidia-6.8, linux-nvidia-lowlatency, linux-raspi, linux-realtime, linux-realtime-6.8, linux, linux-gcp, linux-gcp-fips, linux-gke, linux-gkeop, linux-hwe-5.15, linux-ibm, linux-ibm-5.15, linux-intel-iot-realtime, linux-lowlatency, linux-lowlatency-hwe-5.15, linux-nvidia, linux-nvidia-tegra, linux-nvidia-tegra-5.15, linux-realtime, linux-aws-5.4, linux-gcp, linux-gcp-5.4, linux-gcp-7.0, linux-oem-7.0, minetest, and miniupnpd).

Experience AI evolves with flexible resources for every classroom

Post Syndicated from Ben Garside original https://www.raspberrypi.org/blog/experience-ai-evolves-with-flexible-resources-for-every-classroom/

Experience AI equips young people with a meaningful understanding of artificial intelligence (AI) and machine learning by giving educators the knowledge and confidence to teach these topics in ways that suit their classrooms.

Whether you’re introducing AI to learners for the first time, helping them deepen their understanding, exploring generative AI with them, or integrating AI literacy across the curriculum, Experience AI offers you all the resources you need for free.

Since we started publishing Experience AI resources in 2023, they have been downloaded over a million times in 195 countries, and we have worked with partner organisations in more than 40 countries to train educators to teach AI literacy. Thanks to partners, we have learned a lot about how teachers around the world use the resources in their classrooms, and this has given us direction for what new resources to develop.

The updated suite of Experience AI resources

Many teachers looking for AI literacy resources are not computing specialists and have very busy timetables. Under pressure to deliver more content without more instructional time, what educators need are resources they can integrate into what they already teach. To support them, we’re now offering an updated suite of Experience AI resources that make AI literacy more accessible, flexible, and relevant.

The resources include those co-developed by the Raspberry Pi Foundation and Google DeepMind, alongside those developed independently by the Raspberry Pi Foundation.

Screenshot of the Discover AI resources on the Experience AI website

The new Discovering AI resources, aimed at learners aged 8–12 and learners aged 13–16, are single lessons for introducing the fundamental ideas behind AI. They support educators with learners who have little or no prior knowledge of AI, and include engaging, age-appropriate activities.

Screenshot of Experience AI resources.

From there, our updated Foundations of AI units let teachers support their learners to develop a deeper understanding of how AI systems work, how they’re trained, and how they can be applied to real-world problems.

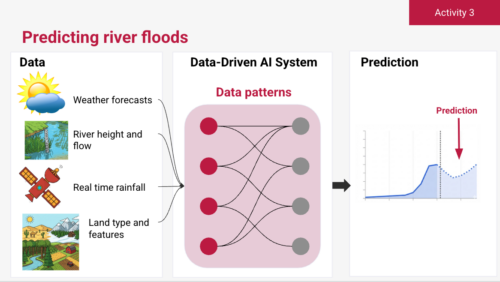
Slide from one of the Experience AI activities exploring AI and a real-world problem such as flood-forecasting.

And a new and growing collection of thematic resources supports teachers and learners to explore AI through cross-subject topics such as creativity, the environment, and critical thinking.

Experience AI now fully reflects our belief that AI literacy needs to be cross-curricular. Application of AI technologies isn’t limited to neat domains or subjects, so learners’ opportunities to understand them shouldn’t be either.

Why we are creating thematic resources

Education systems vary significantly between countries, and in most national curricula, AI literacy is not yet clearly defined. Nevertheless, teachers are both under pressure to deliver this new topic area in their limited classroom time, and eager to rise to the challenge to support their learners.

So we asked ourselves: how can we help educators to teach AI literacy in any subject without additional lesson time, when we cannot create specific resources for every subject in every education system?

Our answer came from educators themselves. Through our network of global partners, we learned that teachers were not waiting for us to tell them in what subjects the Experience AI resources belonged. They were already adapting them to teach AI literacy in all sorts of contexts. For example, we saw that some educators adapted the resource on AI and ecosystems, which we had developed for Biology classrooms, for their Geography classrooms, where it supported similar learning goals.

Photo of a group of educators being trained to teach and use Experience AI resources.

This insight into teachers’ classroom practice prompted us to change our approach.

Now, rather than designing resources for a single subject, we design and organise them in themes that fit across subjects, such as environment, creativity, ethics, and critical thinking. So a resource for exploring the environmental impact of AI data centres could be used in Geography, Physics, Citizenship, or Business Studies classrooms. An activity about AI-generated media could prompt discussions in Digital Literacy, Art, or Computing lessons. The same material supports different curricular goals, depending on how teachers choose to use it.

Helping every educator teach AI literacy with confidence

A key advantage of this new thematic approach is flexibility. Our thematic resources support teachers to:

  • Introduce AI literacy through topics they can easily fit into their subject
  • Integrate AI literacy without additional lesson time
  • Adapt the included activities for different learners and classroom contexts

Like all Experience AI materials, the new resources:

  • Encourage classroom discussions and promote critical thinking and reflection about AI technologies
  • Help learners understand how AI impacts society, not just how AI tools work
Photo of an educator teaching Experience AI in a classroom.

While Experience AI will continue to focus on core AI literacy concepts — how AI systems work, how they are used, and how to think critically about them — the resources we offer will increasingly be:

  • Thematic: Built around real-world topics with broad relevance
  • Modular: Adaptable to different classroom contexts rather than tied to a fixed sequence
  • Differentiated: Designed specifically for learners aged 8–12 and 13–16
  • Varied in format: Full lessons, stand-alone discussion activities, and extended project guides

In this way, we aim to make teaching AI literacy practical and achievable for every educator, regardless of their subject specialism or previous experience of using or teaching about AI.

Share your feedback with us

We’ve tested the new thematic resources with our Experience AI partner, Digital Moment in Canada, who also co-created our Social Media and Flood Forecasting units. Educators’s feedback shows that they value the added flexibility and find the new materials easier to bring into their teaching.

With our new approach, we’re able to offer a more flexible Experience AI programme that supports a wider range of educators, however they want to bring AI literacy into their classrooms.

If you use the resources in your classrooms, please tell us what you think. We’ll continue refining and expanding the Experience AI programme and resources in response to feedback from educators and partners around the world.

Get in touch and share your stories of using Experience AI in the classroom via our email: [email protected]

The post Experience AI evolves with flexible resources for every classroom appeared first on Raspberry Pi Foundation.

The collective thoughts of the interwebz