Backblaze Computer Backup is designed to be simple: install it, and it runs in the background protecting data. For many businesses, that’s enough.
But, IT teams managing large deployments asked for more control over how backup is configured across their environments. We are now introducing two new tools built specifically for that need: Advanced Installer and the Backblaze Command Line Interface, bzcli.
What it does
The Advanced Installer gives IT teams a way to preconfigure and lock down certain client settings during rollout. That means when Backblaze is installed on an employee’s machine, it already has the company’s preferred settings in place—no need for end users to make adjustments.
Admins can:
Lock schedules so backups always run at the right time.
Manage exclusions centrally, avoiding the risk of someone skipping important folders.
Control security preferences to keep things consistent across the organization.
Suppress non-essential desktop notifications.
Instead of configuring machines individually or correcting settings after deployment, IT teams can define standards once and apply them consistently.
For organizations that frequently onboard employees, manage distributed teams, or provide backup as part of a managed service, this reduces variability and support overhead.
Bzcli: Remote configuration and reporting for RMM environments
In addition to the Advanced Installer, Backblaze Computer Backup will have access to bzcli, a new command-line interface designed for enterprise IT teams using RMM and MDM platforms.
Until now, Backblaze’s command-line support focused primarily on installation. Once deployed, there wasn’t a structured way for administrators to modify configuration settings or retrieve information remotely through automation tools. Bzcli addresses that gap.
Configure after installation
With bzcli, administrators can update client configuration settings after deployment using a structured JSON input file.
It supports the same settings available through the Advanced Installer and Preferences interface, including:
Backup schedules
Exclusions
Network controls
Security-related preferences
Notification behavior
This allows IT teams to adjust policies centrally without requiring user interaction.
Designed for automation
Bzcli uses a command-based structure (for example, bzcli configure and bzcli report) with clear flags and predictable output. It’s designed to work cleanly within scripts and automation workflows. The tool is cross-platform and included as part of the standard client installation on both Mac and Windows. It is intended to support environments using tools such as Jamf, Kandji, Addigy, and Microsoft Intune.
Why it matters
As organizations grow, consistency becomes more important. Backup policies need to be enforced reliably. Configuration drift creates risk. Unnecessary notifications create noise.
Advanced Installer and bzcli are designed to reduce that friction.
IT teams can define standards once, apply them consistently, and adjust them when needed, without manual intervention on individual machines.
For teams responsible for protecting company data across large environments, that added control makes deployment more predictable and ongoing management simpler.
Get started with a free 14-day trial of Backblaze Computer Backup today. Or, contact our Sales team to talk about your enterprise deployment today.
There are strong noticeable patterns among these 50 passwords that can be seen easily:
All of the passwords start with a letter, usually uppercase G, almost always followed by the digit 7.
Character choices are highly uneven for example, L , 9, m, 2, $ and # appeared in all 50 passwords, but 5 and @ only appeared in one password each, and most of the letters in the alphabet never appeared at all.
There are no repeating characters within any password. Probabilistically, this would be very unlikely if the passwords were truly random but Claude preferred to avoid repeating characters, possibly because it “looks like it’s less random”.
Claude avoided the symbol *. This could be because Claude’s output format is Markdown, where * has a special meaning.
Even entire passwords repeat: In the above 50 attempts, there are actually only 30 unique passwords. The most common password was G7$kL9#mQ2&xP4!w, which repeated 18 times, giving this specific password a 36% probability in our test set; far higher than the expected probability 2-100 if this were truly a 100-bit password.
This result is not surprising. Password generation seems precisely the thing that LLMs shouldn’t be good at. But if AI agents are doing things autonomously, they will be creating accounts. So this is a problem.
Actually, the whole process of authenticating an autonomous agent has all sorts of deep problems.
Защо съществуват паралелни образователни реалности? Защо за едни училището е едва ли не нещо свещено, за други – нещо несъвършено, но все пак необходимо, а за трети е олицетворение на злото? И в подкрепа, и против училищното образование има достатъчно сериозни аргументи. Доведени до крайност обаче, в някои отношения защитата на училището и тази на домашното образование подозрително си приличат.
За какво ни е училище?
Училището изглежда толкова безусловна даденост, че рядко се замисляме защо е нужно то и дали пък не може и без него. В училище децата (би трябвало да) придобиват базисни знания и умения, които ще са им нужни, за да се справят в света, когато пораснат, за да могат да имат професии, за които е нужна някаква квалификация, както и известна обща култура.
Не всички деца имат възможност да придобият необходимите знания и умения вкъщи – било защото родителите им не ги притежават и съответно не могат да им ги предадат, било защото работят и нямат възможност да се занимават всекидневно с образованието на децата си. А нерядко и двете. Докато възрастните са на работа, децата им трябва да се дянат някъде. Друг въпрос е, че не всички деца имат родители.
Скритата учебна програма
Училището обаче не е просто място за трупане на знания (и „гардероб“, в който родителите да оставят децата си). В социологията съществува понятието „скрита учебна програма“. То означава, че освен на съдържанието, включено в учебните планове и програми, чрез неписани правила училището учи и на други неща.
В скритата програма влиза социализацията, тоест усвояването на обществените норми и на различни социални роли. Училището възпитава в определени ценности – в отношения на йерархия или пък на равенство, в дисциплина или пък в свободно изразяване, в преклонение пред авторитета или в критично мислене, в полови стереотипи.
Скритата учебна програма се осъществява не само чрез образователните изисквания. За нея играе роля например и видът на класната стая – дали мястото на учителя е отпред, или всички са подредени в кръг. В някои по-либерални образователни системи, например финландската, дори може да няма чинове, а учениците да седят по земята или където им е удобно. В такава среда е невъзможно часовете да започват с „Клас стани, клас мирно!“ – както беше в България по времето на социализма (и не само).
Дали има униформи (и какви са те), или няма, също е от значение. Също и кои са портретите на великите личности, които учениците виждат всекидневно. И дали са преобладаващо (ако не и изцяло) на мъже.
Тези функции на образованието го правят мощен инструмент в ръцете на недемократични режими, които посредством училището се опитват да създават „правилни“ хора, приемащи безкритично официалните послания. Професор Красимир Стоянов, преподавател по философия на образованието в Германия, изследва как от началото на войната срещу Украйна Русия систематично индоктринира учениците в официалната идеология:
Извършва го чрез определени съдържания, но и чрез създаването на младежки организации, установяването на определени задължителни ритуали и други подобни мерки.
По времето на социализма децата учеха за Павлик Морозов – момче герой, предало собствения си баща и загинало мъченически. Подобен персонаж има и в нацистка Германия. И в двата случая посланието е едно – „правилният“ човек трябва да е способен да жертва личния си живот и дори семейството си в името на държавата и нейните идеали.
„Още една тухла в стената“… или правоъгълна тухла в кръгла дупка
Френският социален мислител Мишел Фуко определя училището като дисциплинарна институция – редом със затвора, болницата (особено психиатрията), казармата и фабриката. Основната цел на една дисциплинарна институция е да произвежда не личности, а винтчета в социалната машина.
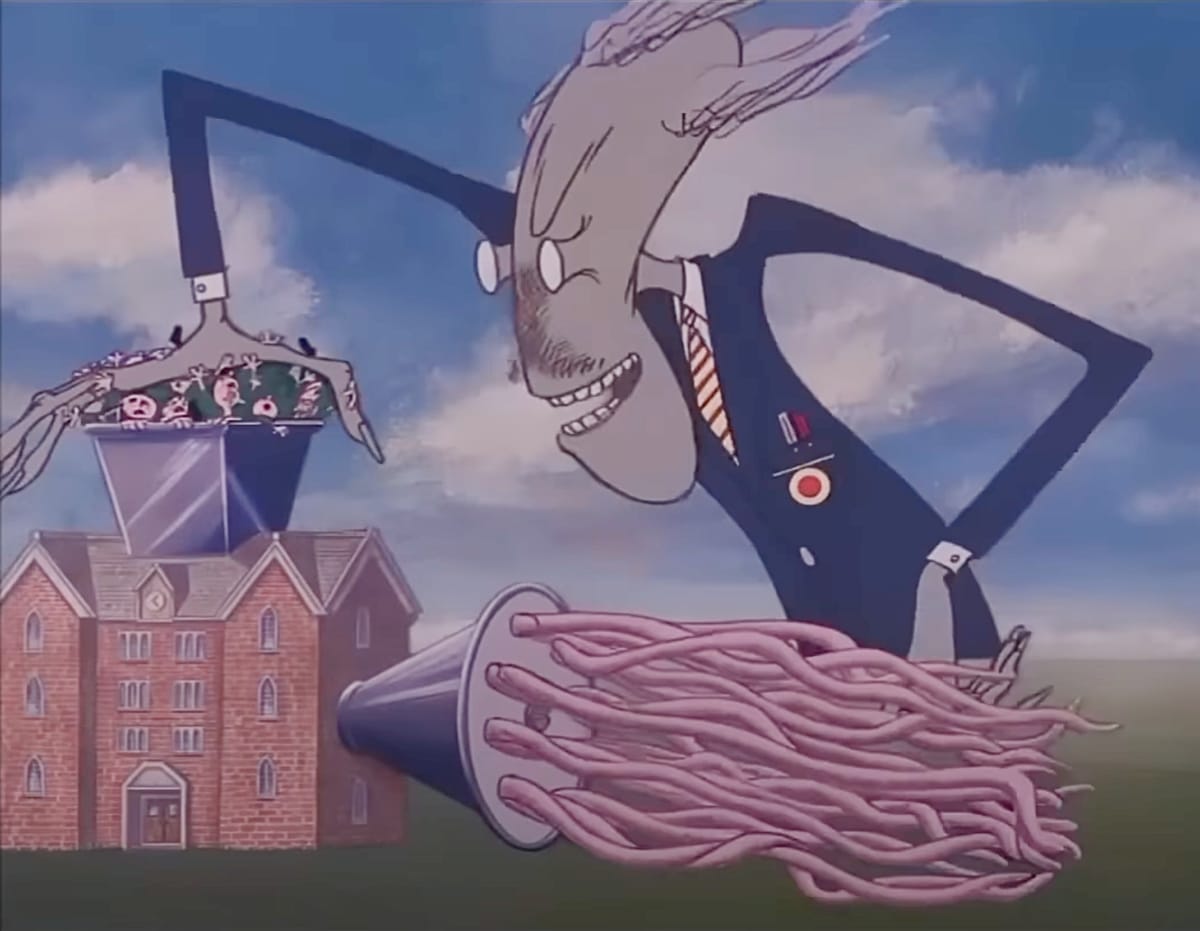
Тази представа за образованието е пресъздадена и в „Стената“ на Pink Floyd. Ако сте гледали едноименния филм, едва ли сте забравили кадрите, в които учениците остават без лица и учителят ги вкарва в месомелачката, където те стават на кайма, докато детски гласове пеят: „Не искаме образование, / не искаме контрол на мисълта / […], всички ние сме просто тухла в стената.“ А може и да сте се припознали (като мен) в учениците, тайно мечтаещи да въстанат срещу обезличаването им.
Концепцията за образованието, пресъздадена от Фуко и Pink Floyd, е характерна за индустриалното общество, в което действително е необходимо да се създават дисциплинирани хора – винтчета в социалната и производствената машина. В постиндустриалните общества обаче са все по-необходими други качества – развита индивидуалност, способност за мислене извън шаблона и за адаптация към променящия се свят.
Българската образователна система продължава да възпроизвежда практиките от времето на индустриалната епоха – дисциплина вместо мотивация, зубрене и възпроизвеждане вместо критично мислене и функционална грамотност. Системата не се справя добре, но идеите тя да бъде „поправена“ на този етап са в стил „още от същото“ – повече дисциплина и повече наказания. Плюс набиването на православни добродетели в ученическите глави. „Продуктите“ на тази образователна система са подходящи обекти за политическа манипулация, но не и пълноценни личности, способни да се справят в съвременното общество.
На всичко отгоре образователната система се опитва да си измие ръцете, прехвърляйки цялата отговорност на семейството върху учениците. Със сигурност сте чували твърдението „Всичко зависи от семейството!“. Ако обаче училището абдикира от усилието да компенсира неравнопоставеността на децата, идващи от семейства с различни възможности, изпълнява ли то основната си задача?
Образование без училище
Ако „всичко зависи от семейството“, защо изобщо децата трябва да ходят на училище, а не се образоват вкъщи? Има родители, които действително са решили да вземат образованието на децата си в свои ръце и смятат, че могат да се справят по-добре от училището.
В сърцевината на концепцията за домашното образование стои идеята за свободата. Свободата обаче може да означава много неща. Тя може да бъде – по Ерих Фром – „свобода за“ и „свобода от“. Освен това чия свобода? На детето, на родителите, на семейството?
„Свобода от“ и „свобода за“
На първо място, домашното образование означава свобода от официалната образователна система. Тази свобода може да е пълна – ако учениците не са записани в български училища, в които да вземат индивидуално изпити, а учат по различни програми. Или частична – децата се явяват на приравнителни изпити към дадено училище, но са в ролята на частни ученици и им е спестена „скритата учебна програма“ – ако не изцяло, то в значителна степен.
Видно от Писанията е, че гражданските, както и църковните власти нямат права, дадени им от Бога, да задължават […] хората да се инжектират с каквото и да е или да изискват да покриват устата, носа, въобще лицето си с маски. Всяка гражданска или църковна власт, която се опитва да принуди хората или техните деца […] да изпълняват подобни нареждания или ги заплашва с глоба, затвор, социален остракизъм или други форми на принуда за това, че не носят маска или не си инжектират някакво вещество в тялото, си присвоява власт, която не е делегирана от Бога, и е тежък грях.
Майка с опит в домашното образование, с която „Тоест“ разговаря, няма нищо общо с евангелизма и не е против ваксините. Но сред семействата, радетели на хоумскулинга, които тя познава, е имало, по нейните думи, „прилична част антиваксъри – още преди COVID“.
Що се отнася до „свободата за“, домашното образование дава възможност на родителите да обучават детето според собствените си разбирания. А разбиранията им може да са различни – докато за едни приоритет е функционалната грамотност, за втори е съобразяването с интересите, талантите или когнитивните особености на децата им, за трети – религиозното възпитание, и т.н. И тук стигаме до следващия въпрос
Свобода за кого?
Когато най-важната цел за родителите е да се съобразят с интересите, талантите и особеностите на детето си, свободата е най-вече за детето. Когато обаче приоритет е религиозното образование и желанието на родителите да предпазят децата си от „греховния свят“, свободата е предимно тяхна. И ако първият вариант, доведен до крайност, може да произведе личност със сериозни пропуски в общата култура и без понятие за собствените си граници, при втория децата може да пораснат като религиозни фундаменталисти или да се окажат отхвърлени, защото не се вписват в ценностите на родителите си.
Впрочем мнението, че родителите трябва да имат пълната свобода да възпитават децата според собствените си ценности и институциите не бива да им се месят, се споделя не само от религиозни фундаменталисти.
В представата за абсолютната свобода на семейството да определя възпитанието на детето си неправителственият сектор се припознава като враг. Един вид, има едни лоши организации, които пречат на родителите да постъпват с децата си, както намерят за добре, и – също като „норвежките джендъри“ – се опитват да им ги отнемат. Иронично, враговете на НПО-тата също се обединяват в НПО-та.
Друг аспект на свободата при домашното образование е свързан с обстоятелството, че за да е възможно то, поне единият родител трябва да си е вкъщи. В общия случай това е майката. Тя може и да работи от дома си, но може и изцяло да е посветена на отглеждането на децата. Това означава, че в повечето случаи финансовата тежест пада върху бащата – но негова е и икономическата свобода. (Еднополови двойки, образоващи децата си у дома в България, не са ми известни.)
Ето така скритата учебна програма на домашното образование може да възпроизвежда традиционалистки и сексистки стереотипи – татко работи, а мама гледа децата.
Между държавната месомелачка и родителската хватка
Фаворизирането на държавния интерес в образованието е за сметка на развитието на личността. В настоящия контекст в България учениците са подлагани на натиск да се подчинят на система, която не само пречупва индивидуалността, ами е и нефункционална.
Фаворизирането на правата на семейството от своя страна е за сметка на правата на детето. То е също така и отрицание на обществения интерес. Да вземем примера с ваксините – решението на родителите дали детето им да бъде имунизирано, или не, има последствия не само за детето им, а за цялото общество. Позабравени болести, като холера, морбили и коклюш, се завръщат, защото все повече хора не искат да се ваксинират срещу тях.
„Никой човек не е остров“, започва стихотворението на Джон Дън „За кого бие камбаната“. Някъде между хората (и семействата) като острови и учениците като „тухли в стената“ е възможно смисленото образование – допринасящо за създаването на пълноценни и адекватни на съвремието личности.
NVIDIA this afternoon reported its earnings for both Q4 of their 2026 fiscal year, and for their complete 2026 fiscal year. And like most NVIDIA earnings announcements over the past few years, it is a doozy. The flagship company for the current AI boom recorded $68 billion in GAAP revenue for Q4’FY26, a 73% year-over-year […]
On February 25, 2026, Cisco disclosed a critical authentication bypass vulnerability in Cisco Catalyst SD‑WAN Controller and Cisco Catalyst SD‑WAN Manager, tracked as CVE‑2026‑20127, that allows an unauthenticated attacker to gain administrative access to affected systems. The Cisco Catalyst SD-WAN Controller and Manager are core components of Cisco’s software-defined wide area networking (SD-WAN) architecture. The issue was originally identified and reported by Australian cybersecurity authorities, who observed real‑world attacks leveraging this flaw.
Customers running these products must urgently upgrade to a fixed release to prevent further compromise. This vulnerability affects the following deployment types:
On-Prem Deployment
Cisco Hosted SD-WAN Cloud
Cisco Hosted SD-WAN Cloud – Cisco Managed
Cisco Hosted SD-WAN Cloud – FedRAMP Environment
At the time of disclosure, Cisco Talos published a report that outlined how malicious actors in the wild leveraged CVE-2026-20127 to gain initial access, then downgraded the software version on the compromised system for post-exploitation activity. After the targeted system had been downgraded to an older vulnerable firmware release, the attackers exploited CVE-2022-20775 to escalate privileges and gain root access to the system. This exploitation in the wild led CISA to issue an emergency directive to Federal Civilian Executive Branch (FCEB) agencies requiring that patches be installed by 5:00PM ET February 27, 2026.
Mitigation guidance
At the time of the advisory’s publication, Cisco does not recommend any workaround strategies for remediation. Organizations running affected instances of Cisco Catalyst SD-WAN Controller or Cisco Catalyst SD-WAN Manager should prioritize upgrading to a fixed version, as outlined below, to remediate CVE-2026-20127.
Affected Cisco Catalyst SD-WAN major version recommendations:
20.11 Release – upgrade to version 20.12.6.1 or above.
20.12.5 Release – upgrade to version 20.12.5.3 or above.
20.12.6 Release – upgrade to version 20.12.6.1 or above.
20.13 Release – upgrade to version 20.15.4.2 or above.
20.14 Release – upgrade to version 20.15.4.2 or above.
20.15 Release – upgrade to version 20.15.4.2 or above.
20.16 Release – upgrade to version 20.18.2.1 or above.
20.18 Release – upgrade to version 20.18.2.1 or above.
20.9 Release – upgrade to version 20.9.8.2 or above (Cisco estimates a patch availability date of February 27, 2026 for this release).
Systems running release versions below 20.9 should be migrated to a newer major version with a fix available.
For the latest guidance, refer to the official vendor advisory.
Artifacts/Evidence Sources and IOCs
For any potentially compromised systems, Cisco recommends specific detection and forensic analysis steps to identify exploitation of CVE-2026-20127. According to Cisco, defenders should look for control connection peering events in Cisco Catalyst SD-WAN logs; Cisco states that all peering events will require manual validation to confirm if the events are valid or not, using the following steps:
Verify the timestamp of each peering event against known maintenance windows, scheduled configuration changes, and normal operational hours for your environment.
Confirm the public IP address corresponds to infrastructure owned or operated by your organization or authorized partners by cross-referencing against asset inventories and authorized IP ranges.
Validate the peer system IP matches documented device assignments within your Cisco Catalyst SD-WAN topology.
Review the peer type (vmanage, vsmart, vedge, vbond) to ensure it aligns with expected device roles in your deployment.
Correlate multiple events from the same source IP or system IP to identify patterns of reconnaissance or persistent access attempts.
Cross-reference event timing with authentication logs, change management records, and user activity to establish whether the connection was initiated by authorized personnel.
Rapid7 customers
Exposure Command, InsightVM, and Nexpose
Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-20127 with authenticated checks expected to be available in the Feb 26 content release.
Data has become an indispensable strategic asset for the entire financial services industry, driving innovation and competitive advantage in an increasingly digital marketplace. At Swiss Life Germany, maximizing the value of this asset means empowering internal teams to derive actionable insights and deliver personalized financial solutions to diverse clientele. This led to the need to establish seamless data sharing workflows that enhance cross-departmental collaboration while maintaining strict security and compliance standards. To accomplish this, Swiss Life Germany decided to implement advanced data processing and governance capabilities using Amazon SageMaker.
Integrating SageMaker into a highly regulated enterprise environment required aligning the service’s agility with Swiss Life’s rigorous infrastructure as code (IaC) automation standards. This post demonstrates how Swiss Life Germany addressed these sophisticated deployment requirements by developing a custom Terraform pattern designed specifically for platform engineers and data architects.
Swiss Life Germany cloud journey
Swiss Life Germany is a leading provider of customized pension products and financial advice. Building on over 100 years of delivering insurance, retirement planning, and wealth management solutions, a key driver of the company’s recent evolution was the strategic transition from legacy on-premises data centers to a modern, cloud-centric architecture. After an extensive evaluation of various providers, Swiss Life Germany selected Amazon Web Services (AWS) as the strategic foundation to modernize their data operations. By using AWS, the organization was able to transition from capital-intensive data centers to a flexible pay-as-you-go model, significantly reducing the operational costs.
Following their comprehensive AWS cloud migration over the last two years—combining 30% re-platforming with 70% lift-and-shift strategies—Swiss Life Germany modernized infrastructure management through IaC. The company introduced the governance concept of an IT System. An IT System is a fundamental unit of management that defines a software component regardless of its origin. Whether a component is purchased from a vendor, self-developed or consumed as software as a service (SaaS), it’s integrated into this single governance structure. This ensures that off-the-shelf products and custom-coded applications are held to the same high standards of visibility and accountability. Every IT system is required to maintain specific attributes that allow for seamless oversight such as unique identifiers, assigned ownership and the associated AWS resources logically grouped under the IT System they support.
Where traditional approaches would store and expose this information in configuration management database (CMDB)-like systems to store static snapshots of asset data, Swiss Life adopted a more dynamic model. By using GraphQL API as a unified meta-model, the company queries application data directly from its primary source systems. This approach eliminates the delays common in batch-processed databases, ensuring maximum freshness. The API serves as a single entry point for infrastructure data, documentation, organizational metadata, and even inter-application dependencies. The transparency and automation gained through this everything-as-code and API-first approach provided a blueprint for the Swiss Life Data Platform: complete transparency, reproducibility, and end-to-end automation.
This robust technical foundation served as a catalyst and prerequisite for Swiss Life’s broader strategic goals and governed framework.
Defining the vision for a unified data solution
With the architectural foundations in place, the next challenge was to establish efficient data flows from production systems through data engineering teams to end users across various business divisions, with hundreds of specific use cases demanding attention.
For instance, Swiss Life’s customer portal specialists had to validate the effectiveness of campaign management and push notification systems in real-time, requiring secure and immediate access to interaction data.
Security requirements added another layer of complexity, because Swiss Life’s solution needed to incorporate robust compliance standards including two-factor authentication, session-based access controls, and granular row and column-level security protections.
To align with the overarching Swiss Life Germany cloud strategy, the company aimed to build a modern data solution atop their existing AWS data and analytics services. AWS introduced SageMaker to Swiss Life Germany following its announcement at AWS re:Invent 2024. A proof-of-concept quickly validated that this was the right tool to advance Swiss Life’s data journey. By deploying a fully automated framework, Swiss Life Germany sought to create a secure, compliant framework with SageMaker democratizing data access for authorized users, ultimately enabling faster business insights and more responsive customer experiences across the entire data environment.
Having met the infrastructure requirements, let’s look at what SageMaker looks like for end users and how data platform administrators can control access and resources at a granular level.
Users and their types of projects
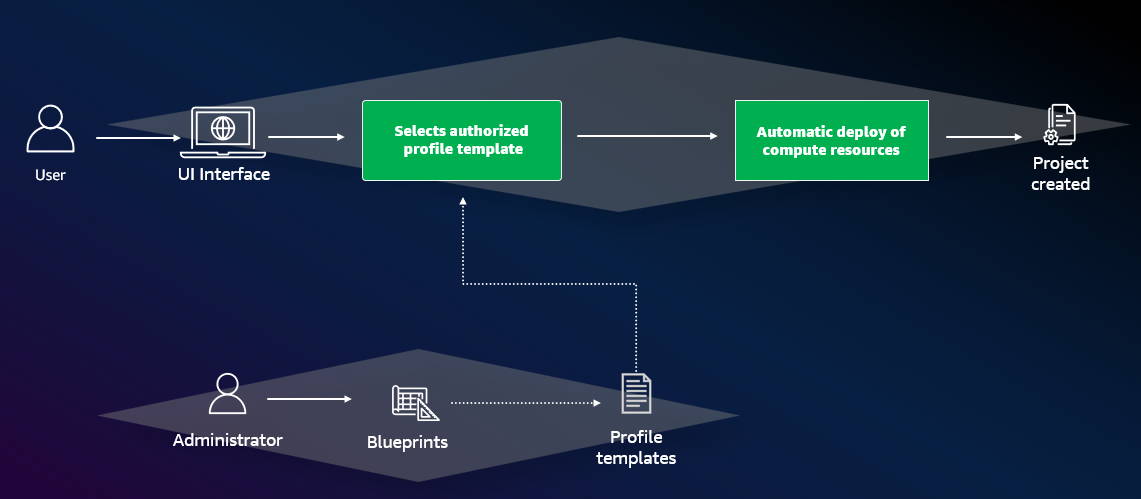
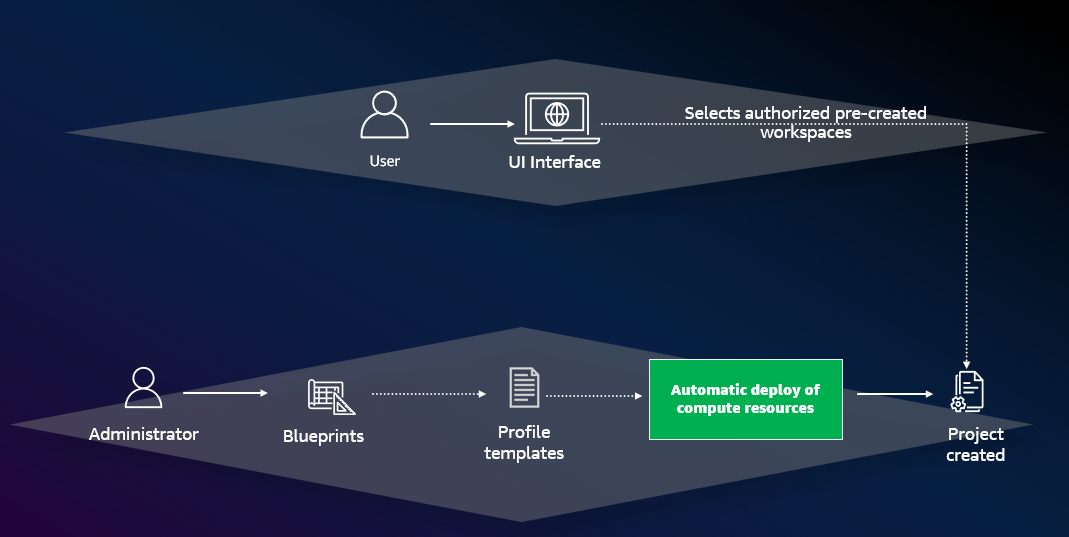
A typical end user experience within Amazon SageMaker Unified Studio starts with creating a project. A project is a logical boundary within a domain where the data teams can collaborate and work on a business use case. Administrators would provision the blueprints and project profile templates for the data teams, as shown in the following figure.
However, at Swiss Life, they have extended the data platform administrator’s role to also create projects so they can maintain regulatory compliance and remove initial onboarding hurdles. The end user experience in SageMaker Unified Studio is simplified with data teams selecting their respective projects to work on a business initiative, as shown in the following figure.
To implement this solution effectively, Swiss Life identified different user groups:
A solution team developing an IT System that can act as producer or consumer of data assets.
A data scientist doing advanced data processing. They will most likely consume a lot of data assets and might produce some high aggregated data assets. The data processing software is also categorized as an IT System.
Business users who have some SQL skills and want to process data to get insights for their daily business.
A platform team administering the data platform. They provide core services to all users to make participation as straightforward as possible.
A data officer who wants to have a single point of interpretation for data.
Given this diverse set of user groups, the resulting data platform had to support a federated data organization with a centralized governance, decentralized data stores and data-processing organized at the IT System level. This architecture means the SageMaker management account—which orchestrates the data domain—contains no actual data, instead, data and compute resources reside in the individual IT System AWS accounts. Swiss Life’s implementation distinguishes between two fundamental project types:
IT System projects (for technical users)
Team projects (for non-technical users)
Swiss Life decided to align team projects with specific organizational units and operate them without staging environments, providing dedicated workspaces for departmental data initiatives. In contrast, IT System projects are associated with specific solutions such as customer portal or CRM systems. These follow a structured staging methodology, with each solution team managing dedicated DEV, TEST, and PROD environments to maintain proper development lifecycles and quality control.
This federated architecture is designed to handle the immense scale and diversity of Swiss Life’s data landscape. Swiss Life’s data platform would then aim to provide unified access to over 180 database servers with over 1,800 databases and 18 thousand tables across all stages (DEV, TEST and PROD).
In this post, we focus on the IT System projects.
How Swiss Life built the automation framework
Because Terraform is the preferred IaC tool across Swiss Life Germany, the team faced an interesting architectural challenge: while the existing infrastructure framework incorporates numerous AWS services that are readily supported by Terraform, SageMaker required a custom integration approach to align with Swiss Life’s advanced automation patterns.
Rather than adopting a manual ClickOps approach to infrastructure management, Swiss Life developed an innovative solution to keep the entire infrastructure—including SageMaker—within their Terraform automation, preserving key benefits like state management. The team accomplished this by using Terraform’s AWS Lambda invoke function resource with a create, read, update, delete (CRUD) lifecycle scope. By using this approach, the organization could maintain a single source of truth for infrastructure, while accommodating specific requirements of SageMaker. This component is called the Management Lambda and it serves as a bridge between Terraform’s declarative configuration and SageMaker, so that Swiss Life can provision, modify, and decommission Amazon SageMaker resources through established Terraform workflows.
The following is the snippet of a new domain creation using Terraform and Management Lambda:
Using this approach, Swiss Life successfully automated every aspect of deploying a complete SageMaker domain installation within the Swiss Life cloud data platform. The automation encompasses the entire domain creation process, using the SageMaker domain unit feature as an organizational framework for diverse project portfolio.
Deployment architecture
Let’s dive deeper into the individual steps of the automation process itself. As said, all resources within SageMaker are controlled by the Terraform-invoked Management Lambda whereas other resources are directly managed by Terraform itself. The Management Lambda and SageMaker resources such as domains, metadata fields and others live in the central SageMaker account. Users of the data platform have their own AWS accounts. To start with, AWS Lake Formation had to be enabled across all AWS accounts, which could then act as consumer or provider to the platform. Using the established AWS Landing Zones mechanism, this was done by a single deployment to the management account. This early step also verified the management role being present in all accounts and assumable by the Management Lambda.
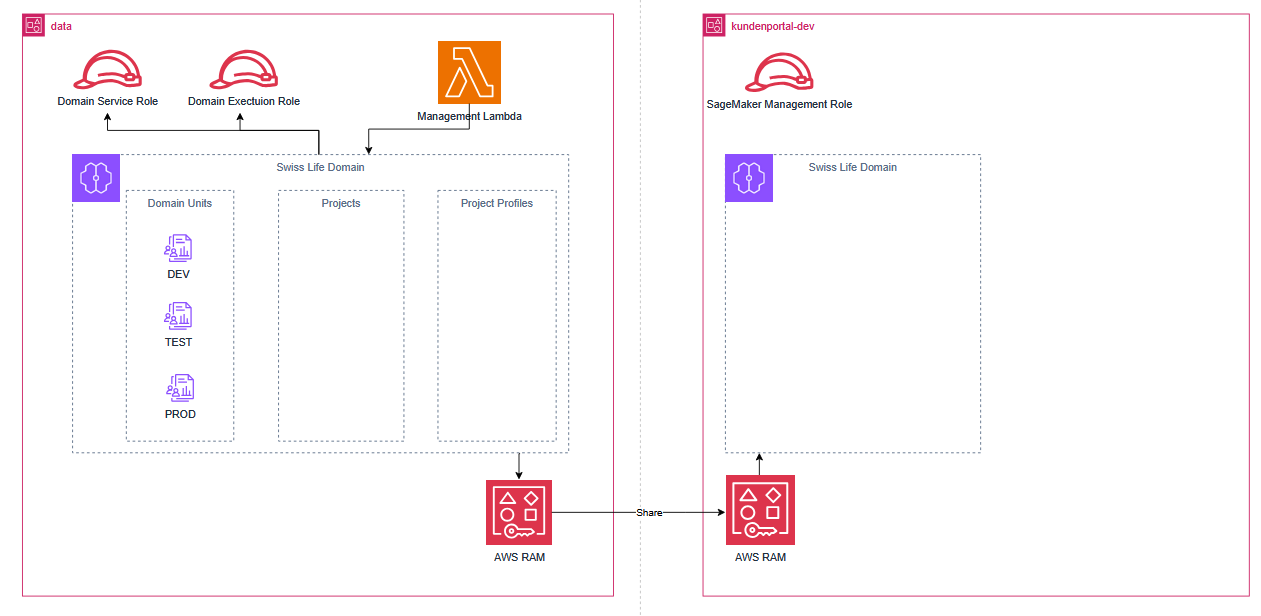
The following steps are used to set up Swiss Life’s data platform from scratch, as shown in the following diagram:
The Management Lambda is deployed to Swiss Life’s designated SageMaker account. This Lambda function uses the described CRUD pattern for all subsequent SageMaker-specific operations.
The domain provisioning begins by creating the service and domain execution roles, after which the Management Lambda creates the domain and uses these roles. During this step, administrative users and their associated permissions are also configured.
Upon successful domain creation, the Lambda function returns the domain identifier as output. This identifier is then used to let all AWS accounts of the company join this domain. These can now act as providers or consumers on the platform, resulting in a frictionless onboarding of teams.
Because Swiss Life decided to stage data products in a single domain, the DEV, TEST, and PROD domain units are then created, establishing the hierarchical structure under which IT System projects are subsequently created in the next implementation phase.
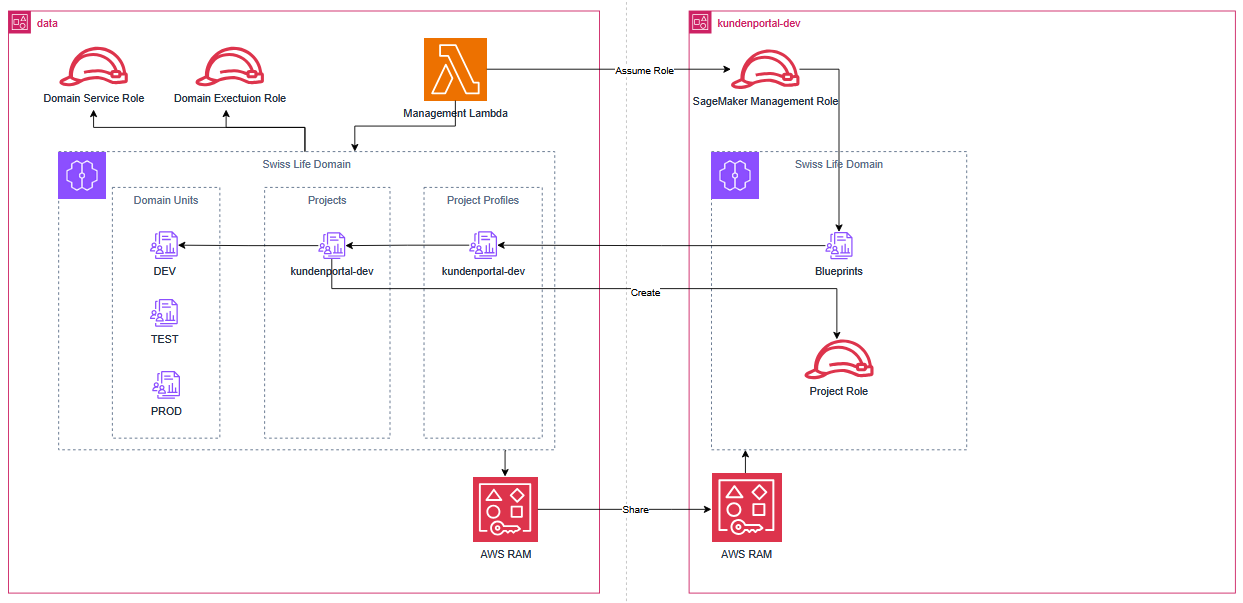
All projects and teams with the necessary prerequisites set up are then created automatically. This is done by using the enterprise GraphQL API mentioned to retrieve all IT products, their teams and roles. With that, each team already has their ready-to-use project in place upon singing into the platform. In detail this process looks like the following:
Continuing with the earlier example: the customer portal team needs to share their data with others in the organization and is using their dedicated project for this purpose. The process is shown in the following figure.
The deployment initiates with a cross-account role assumption by the Management Lambda to activate the blueprint configuration in the team’s AWS account. A standardized creation process was built to help facilitate all accounts are configured identically, maintaining consistency across the environment.
Next, a project profile specifically tailored for the customer portal project is created. This profile establishes the foundational settings and permissions framework that will govern the project’s operations.
With the profile in place, the actual project within this previously established project profile can now be provisioned, instantiating the working environment, where data sharing and collaboration will occur. This results in an identical amount of project profiles and projects in the SageMaker Unified Studio domain.
Finally, an automated membership management process is triggered. The system again queries Swiss Life’s Enterprise GraphQL API to identify all members of the solution team and automatically adds them as project members with appropriate permissions. This process executes daily, to help ensure that project access permissions remain current and accurately reflect team composition changes.
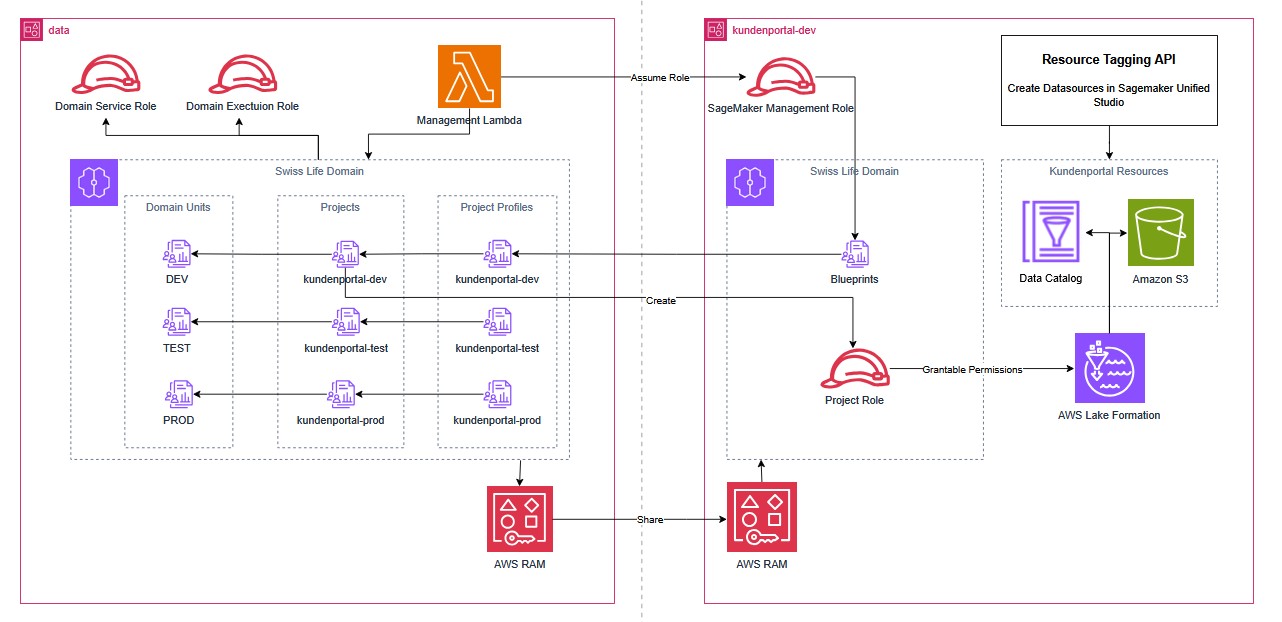
In the third and final deployment step, the user experience is enhanced by making the data platform immediately usable for teams in production. When teams and their members first access the domain URL, they find a project environment already populated with all necessary assets, so they can begin working without delay. This is accomplished through the following steps, shown in the following figure:
An automated discovery process is triggered that identifies all Amazon Simple Storage Service (Amazon S3) buckets and AWS Glue assets associated with the specific customer portal IT System. This inventory is created by using the AWS Resource Tagging API with specific filters targeting these asset types, so that all relevant resources for exactly that IT System are captured.
When identified, all discovered S3 buckets are registered as data lake locations within the platform. For each location, they create an AWS Identity and Access Management (IAM) role with precise access permissions, adhering to the least privilege security model.
Then grantable permissions are granted to the SageMaker project role for these assets, establishing a permission delegation framework that allows project members to manage access within their project scope—managing cross project access—while maintaining overall governance.
Finally, the AWS Glue databases are added as data sources within the project. These data sources are configured with daily synchronization schedules to automatically load new metadata into SageMaker, helping to ensure that catalog information remains current without manual intervention.
What a team needs to start with all of this
The overarching goal throughout this implementation has been to simplify the adoption process for the internal data teams. To ensure the data teams could immediately use the powerful capabilities of SageMaker without needing to manage its underlying architecture, Swiss Life Germany streamlined the experience by pre-packing the entire onboarding process into a high-level Terraform module. Teams can then use the module to deploy a complete, production-ready environment with minimal configuration, accelerating their path from setup to insight.
The following is an example of the code used by the module.
To initiate this, the data teams define their basic parameters such as network configuration or their IT-System identifier as outlined previously and submit a pull request in the central Git repository. After the Swiss Life data platform team reviews and approves the request, the automated processes run in the background, preparing the complete environment. This automated approach has reduced deployment time for new environments from several weeks of manual coordination to under 20 minutes.
Rather than requiring users to understand the intricate deployment steps and managing the infrastructure, the automated deployment process empowers business units, like the customer portal team, to focus on deriving insights. At the same time, the Swiss Life Germany data platform team also maintains precise control over resource allocations, access rights and cost management.
Future enhancements
Looking ahead, Swiss Life plans to elevate its automation to a higher level of business abstraction. The next major enhancement focuses on removing the requirement for teams to request specific technical assets. Instead, the vision is to implement an intuitive interface where teams can specify the business terms or data domains they require. The system will automatically identify and provision the correct underlying technical assets associated with those business definitions.
This semantic layer will create a more natural interaction model, so that business users can think and work in familiar concepts rather than technical constructs. For example, rather than requesting access to specific S3 buckets or AWS Glue databases, a marketing analyst might indicate they need customer interaction data or campaign response metrics. An automated system will then map these business terms to the appropriate technical resources, provision access, and configure the environment accordingly.
By elevating automation to this business terminology level, Swiss Life aims to further reduce friction in the data access process while maintaining its robust security and governance framework. This evolution represents Swiss Life Germany’s commitment to continuously improving how data serves the business, making sophisticated data capabilities increasingly accessible to all parts of the organization.
Conclusion
Through the comprehensive automation of Amazon SageMaker, Swiss Life Germany has transformed their usage of data from a complex technical challenge into a streamlined business enabler. By using AWS services and their innovative Terraform-Lambda integration approach, Swiss Life created a secure, compliant data platform that maintains governance while democratizing access across the full organization. The automated deployment process helps ensure consistency across environments while dramatically reducing the technical knowledge required for teams to begin using advanced data capabilities. Business units, such as the customer portal team, can now focus on deriving insights rather than managing infrastructure, accelerating data-driven decision making throughout the company. This implementation represents a significant milestone in Swiss Life Germany’s cloud journey, demonstrating how thoughtful automation can simultaneously enhance security, improve operational efficiency, and accelerate business outcomes.
As of today, 5 organizational unit teams and 15 IT System teams were onboarded to the platform. To speed things up, Swiss Life has decided to onboard all 180 database clusters and consume data using SageMaker over the coming months. This expansion is designed to enable teams to use the data platform and enhance the efficiency of data discovery and data sharing processes across the organization.
This post is cowritten by Julius Blank from ProGlove.
As software-as-a-service (SaaS) platforms grow, balancing speed of innovation with strong security and tenant data isolation becomes critical. While the same AWS Identity and Access Management (IAM) mechanisms secure both shared and dedicated environments, establishing a hard security boundary is often easier in an account-per-tenant model because the account itself becomes the isolation boundary. In shared-account deployments, you instead rely on resource-level boundaries such as tenant-scoped IAM policies and data partitioning. This multi-tenancy increases architectural and operational complexity and can introduce security challenges if safeguard mechanisms are not properly designed and enforced. By adopting an account-per-tenant model on Amazon Web Services (AWS), you can achieve clearer security boundaries, streamlined ownership of services, and more transparent cost attribution, but this comes at the expense of increased investment in platform automation.
At ProGlove, we build smart wearable barcode scanning solutions that connect frontline workers to digital workflows. Our scanners integrate with Insight, our AWS based SaaS platform, to provide real-time process visibility. This helps customers in manufacturing, logistics, and retail improve their productivity, reduce errors, and enhance ergonomics on the shop floor.
This post describes why we chose a account-per-tenant approach for our serverless SaaS architecture and how it changes the operational model. It covers the challenges you need to anticipate around automation, observability and cost. We will also discuss how the approach can affect other operational models in different environments like an enterprise context.
Why multi-account?
Many SaaS providers begin their journey with a straightforward, dedicated deployment model, often with one AWS account per tenant. This approach makes initial implementation straightforward and limits the scope of issues, but as the platform scales, operational overhead and inefficiencies from idle or underutilized resources increase. These inefficiencies can be mitigated with serverless architectures that scale automatically to demand. Over time, providers often look to shared or multi-tenant models to consolidate operations and improve cost efficiency. However, this shift introduces new challenges as the number of tenants and services grows:
Blast radius – An accidental misconfiguration or vulnerability could expose multiple tenants.
Quota limits – Tenants in a single AWS account share the same quotas.
Operational complexity – Shared infrastructure makes it difficult to reason about ownership of resources.
Customization limits – Making changes for one tenant risks impacting others.
Cost visibility – Attributing resource usage to individual tenants is challenging.
Choosing between a dedicated or shared model is ultimately a trade-off. Dedicated deployments are more straightforward to build but require investment in SaaS operations and orchestration to manage at scale, whereas shared models reduce operational overhead but increase architectural and management complexity.
AWS recommends a multi-account strategy to organizing your AWS environment. At scale, the AWS account boundary is the easiest way to implement isolation. Accounts are fully isolated containers for compute, storage, networking and more, with no shared scope unless you explicitly configure it.
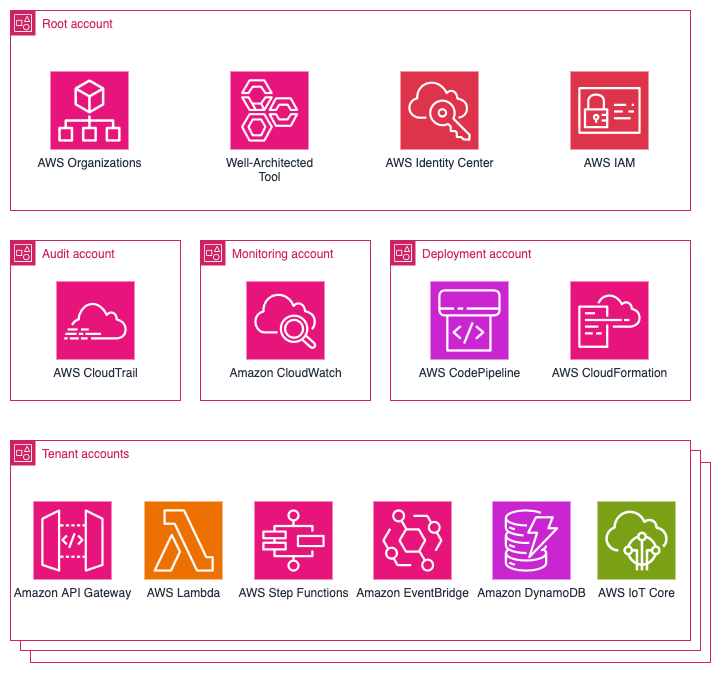
Working backwards from our use case, we decided to take this model to its logical extreme: every tenant gets their own AWS account. The services they consume are deployed directly into that account. In that account, we deploy the full set of microservices that the tenant requires. These services run exclusively with that tenant’s data and configuration. At our current scale, ProGlove manages approximately:
6,000 tenant accounts, where approximately 50% are active and deployed
40 microservices, each with multiple AWS Lambda functions and supporting resources
That translates to over 120,000 deployed service instances and roughly 1,000,000 Lambda functions in production. The following diagram shows an overview of the main services used in our platform.
Benefits of the account-per-tenant model
This model brings several benefits that directly support security, agility, and operational clarity, including a strong isolation model, simplified mental model, customization per tenant, and transparent cost attribution. Tenant data is not co-located. Each account has its own storage, compute, and permissions. If a security issue, runaway process, or misconfiguration occurs, the impact is limited to that tenant’s account while other tenants remain unaffected. For developers, they don’t need to think multi-tenancy as a deployed service instance always belongs to exactly one tenant. This reduces cognitive load and simplifies debugging. Developers can easily be provided with isolated, production-like tenant accounts to eliminate the gap between development and production environments. You can modify, test, and migrate individual accounts independently. This helps to create tailored deployments, such as activating premium features for certain tenants, without impacting the overall system.
AWS Cost Explorer and linked accounts make it straightforward to report and charge back costs on a per-tenant basis. For SaaS providers with consumption-based pricing models, this becomes a strong advantage.
When conducting an AWS Well-Architected Framework review together with AWS, we found that many items from the operational excellence as well as the security pillar didn’t even apply to our setup anymore. This made completing those review sections quick and straightforward.
Challenges and trade-offs
The account-per-tenant model, like most architectural choices, involves trade-offs. Although the model provides strong isolation, it introduces challenges in platform operations. The approach shifts complexity away from application development to platform development.
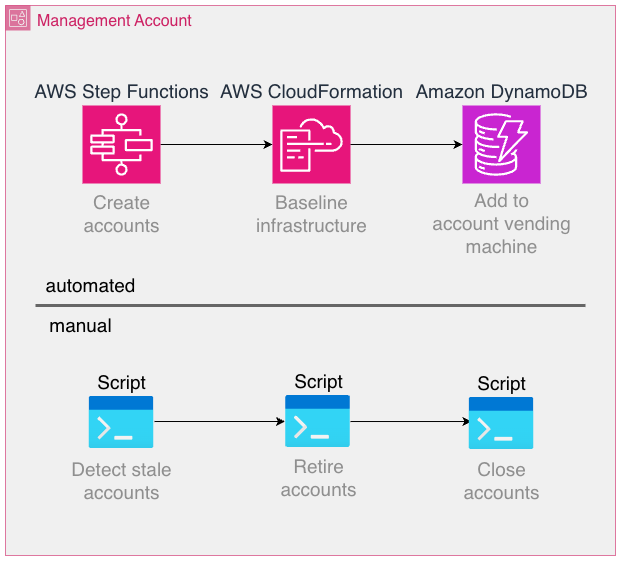
Provisioning, configuring, and managing thousands of accounts isn’t feasible manually. Automation of account creation, baseline setup, IAM roles, guardrails, and service enablement is mandatory. We rely on AWS Organizations, its service control policies (SCPs), and AWS CloudFormationStackSets, as well as custom tooling to handle this.
Some of the involved workflows lend themselves well to automation, whereas others can be implemented more effectively using traditional scripting and manual operations, as long as the overhead introduced is low enough. For example, account creation is a fully automated process using AWS Step Functions, but the retirement and closure of accounts are performed manually through regularly run scripts.
Some AWS services are billed per provisioned resource and independent of utilization as opposed to fully scaling to zero when not used. Prominent examples are Amazon Elastic Compute Cloud (Amazon EC2) or Amazon Relational Database Service (Amazon RDS), where resources need to be provisioned to use the service. Even the smallest EC2 instance type is charged at around USD $3, which adds up to USD $3,000 when deployed into 1,000 accounts. By contrast, serverless offerings such as AWS Lambda or Amazon DynamoDB automatically scale based on actual usage, minimizing idle resource costs. Although the per‑invocation or per‑request pricing for serverless services can seem higher, these models often offset the operational overhead and resource wastage associated with always‑on infrastructure. In any case, costs should be carefully modeled, measured, and optimized.
Monitoring infrastructure across accounts and Regions at scale is significantly harder than monitoring a handful of accounts. Observability tooling should be centralized, but without reintroducing the very risks that accounts are meant to isolate. It’s important to point out that Amazon CloudWatch offers greatly improved cross-account observability features today than when we started, for example, the Observability Access Manager.
Developers, operations teams, and platform services and tools need to operate across accounts on a daily basis. This requires a robust identity model with IAM roles and cross-account trust policies. If not designed carefully, this can become a source of complexity and security risk. Also, make sure to follow the best practice of avoiding long-lived credentials because these introduce a major security threat and monitoring effort if deployed into many accounts. AWS service limits are enforced per account. In a shared-account model, you monitor a single set of quotas. In an account-per-tenant setup, quota management becomes distributed and harder to predict. Proactive quota requests and monitoring are essential. For example, AWS Lambda employs a quota for the number of concurrent executions that functions in a single account share. In case a tenant is under heavier load, it’s likely for the corresponding account to experience throttling errors of Lambda functions, which is why it’s essential to provide a single pane of glass view to keep track of the quota usage and adapt as necessary. Although multi-account strategies are common at the enterprise level, adopting them at the SaaS tenant level is less common. Patterns, tooling, and reference architectures are still evolving, which means building custom solutions becomes necessary. Make sure to research available resources and consult AWS so you don’t reinvent the wheel.
Scaling observability across tenants
Observability can become a challenge in this architecture. If each tenant account emits its own logs, metrics, and traces, operational visibility becomes fragmented. For enhanced cross-account capabilities, we used a third-party observability solution. As an example, we forward telemetry (logs and metrics) to a central application where we can configure multi-alerts that are defined one time and applied to tenant accounts individually. This not only reduces cost but also simplifies the operational experience. Engineers interact with a single view, while underlying telemetry still originates from isolated accounts.
It’s vital to use tags whenever possible to correlate telemetry data as well as to use a consistent tagging and naming convention. Depending on the scale of operations, consider using AWS Organizations tag policies to enforce a consistent scheme. As an example, we include fields for the source AWS account ID in most metrics and logs to make sure we can easily drill down into the data for one particular tenant.
Key takeaways:
Don’t replicate per-account alarms blindly. Use streaming and aggregation.
Use tags for consistent context across thousands of instances.
Stay current with AWS feature releases with the AWS News Blog: metric streams, Amazon EventBridge integrations, Amazon CloudWatch Observability Access Manager, and other offerings can streamline your observability stack.
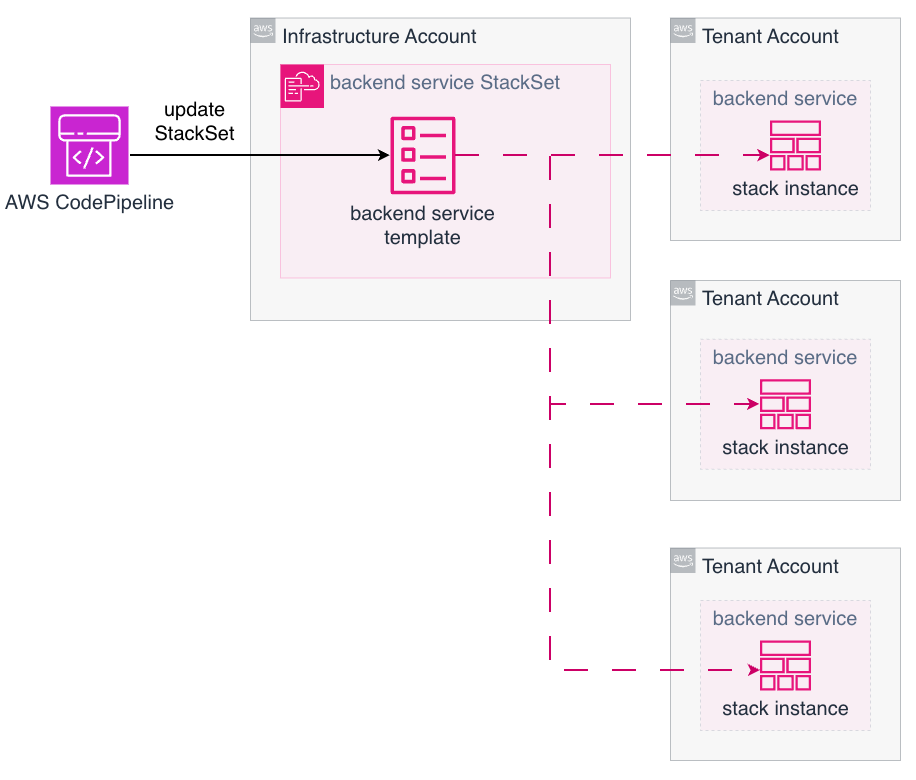
Deploying microservices into one AWS account is straightforward. Deploying the same service into thousands of accounts requires a different approach. Our application code is stored in a monorepo, which helps us to enforce the same version of libraries or Lambda layers among others. The following diagram illustrates how we update many tenant accounts using AWS CodePipeline combined with AWS CloudFormation StackSets to deploy the applications. Each pipeline execution updates many target accounts in parallel, with only a single StackSet update operation in a central account.
While this provides the necessary scale, it also introduces new failure modes:
Partial rollouts – If one account fails to deploy, rollback or retry strategies need to be defined and tested.
Pipeline duration – Large-scale updates can take significant time to propagate.
Tooling maturity – StackSets are powerful but still evolving, and operational edge cases are possible.
In practice, this requires investing in platform engineering. A dedicated team builds and maintains internal tools that abstract deployment complexity away from service developers. Developers remain focused on business logic, and the platform team takes care of consistency and reliability across accounts.
Cost management
Cost modeling changes significantly with this architecture. In a shared account, many costs are pooled, making per-tenant attribution difficult. In a account-per-tenant model, costs are naturally segmented by account .On the positive side, tenant-specific cost reporting is trivial. SaaS providers can align billing directly with AWS usage and even get monthly reporting per tenant automatically through AWS billing.
Costs that scale per account needs to be carefully considered. At scale, even small charges per resource become meaningful. For example, collecting metrics from thousands of accounts requires careful planning and the chosen approach has great influence on costs. At this scale, it isn’t feasible to use standard observability tooling out of the box because the volume of collected data can make per‑account costs economically unsustainable. Instead, focus on understanding which metrics you need to monitor and select an observability approach that allows you to implement that. As a recommendation, evaluate cost multipliers early. Services that scale linearly with the number of accounts should be avoided where possible. Make sure to verify your assumptions with actual measurements.
Operational considerations
To succeed with this model, you need to be prepared to invest in platform capabilities:
Account management – Automate everything from creation to decommissioning.
Baseline guardrails – Enforce compliance and security controls using SCPs and a strict IAM management.
Developer training – Make sure teams understand the scope and boundaries of their services.
CI/CD investment – Pipelines need to scale to thousands of accounts without blocking innovation.
Observability discipline – Monitoring needs to be consistent, centralized, and cost-effective.
Conclusion
In this post, we described how ProGlove implemented a large-scale account-per-tenant model on AWS and how that model shifts complexity from service code to platform operations. This is a trade-off that requires more platform automation, scalable CI/CD pipelines, and disciplined observability practices. The benefits are strong tenant and workload isolation, transparent costs, and severely reduced blast radius. These benefits are key for platform providers operating at scale with a strictly limited operations team size. Managing thousands of AWS accounts with three people might sound impossible. But with the right architectural choices, every new workload adds only marginal operational load while the platform absorbs the exponential scale. The team size stays constant, and efficiency grows with every account added. If security, compliance, and clarity are top priorities, this approach can serve as a strong foundation for your platform. Working backwards from these requirements can help you achieve the same balance: scaling your tenant base drastically, without scaling your operations team at the same rate.
The stated support periods for the 6.6, 6.12, and 6.18 kernels has been extended.
The 6.6 kernel will be supported with stable updates through the end of
2027 (for four years of support total), while 6.12 and 6.18 will get
updates through the end of 2028, for four and three years of support.
Ahead of MWC, AMD is introducing its EPYC 8005 “Sorano” series of processors. Aimed at the telco and edge markets, these efficiency-focused chips have up to 84 Zen 5 CPU cores
Hospitals invest heavily in physical security: Clinical areas are access-controlled, sensitive rooms are locked, and patient records are governed by strict handling procedures. Network exposure does not always receive the same level of scrutiny.
Rapid7 Labs identified more than 30 UK-based systems responding to DICOM requests over Port 104, the default port used for medical imaging traffic. These systems were reachable from the public internet at the time of observation. Project Sonar was used to confirm service responsiveness only; no attempt was made to access patient records or exploit the systems.
When Port 104 is reachable from outside trusted networks without VPN restriction or encryption, the imaging service can be detected through routine internet scanning. This type of exposure matters because protocols like DICOM were developed for use within protected clinical environments where network access is already controlled.
Research into medical imaging infrastructure has found that when security best practices are not implemented, imaging systems and their acquisition gateways are placed on networks in ways that expose them to cybercriminal discovery. In one study of publicly accessible PACS (picture archiving and communication systems) servers, researchers reported that systems using default configurations or lacking appropriate network controls responded to internet scans and contained metadata such as patient identifiers, and the lack of basic protocol safeguards made them susceptible to data reconstruction and modification.
Why should DICOM not be internet-facing?
DICOM, or digital imaging and communications in medicine, is the international standard used to format, store, and transmit medical imaging data. It governs both the image itself and associated metadata, which can include patient identifiers, study details, acquisition parameters, and device information. Imaging modalities such as CT scanners and MRI machines use DICOM to send studies to Picture Archiving and Communication Systems (PACS), where images are stored and later retrieved by radiologists and clinicians.
DICOM operates at the application layer. Port 104 is the traditional default port associated with DICOM services, but the protocol is not limited to that port. PACS systems and imaging services may also communicate over web ports such as 80 or 443, and in some cases expose web-based or administrative interfaces over additional ports. In our broader research, we identified more than 15 PACS devices that were externally reachable, including systems accessible over standard web ports.
⠀
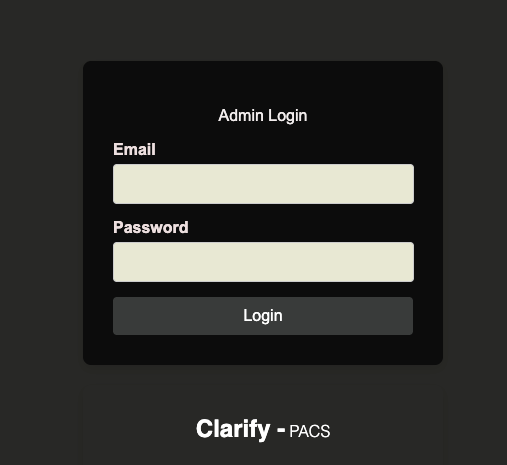
Figure 1: Clarify – PACS admin login portal.
⠀
In standard hospital deployments, DICOM services are intended to operate within segmented and trusted clinical networks. The protocol historically assumed that the surrounding network would provide access control and protection. When imaging systems or PACS services are reachable from public IP space, whether over Port 104 or web-based interfaces, they may respond to protocol negotiation or HTTP requests and disclose service-level information. In some configurations, metadata or system details can be retrieved without strong authentication controls.
That condition does not necessarily imply full access to imaging archives. It does mean that clinical infrastructure is externally discoverable and capable of interaction beyond its intended network boundary. The risk arises from that exposure, particularly when it is unintended or unmonitored.
Exposed DICOM servers in the UK: What Rapid7 Labs found
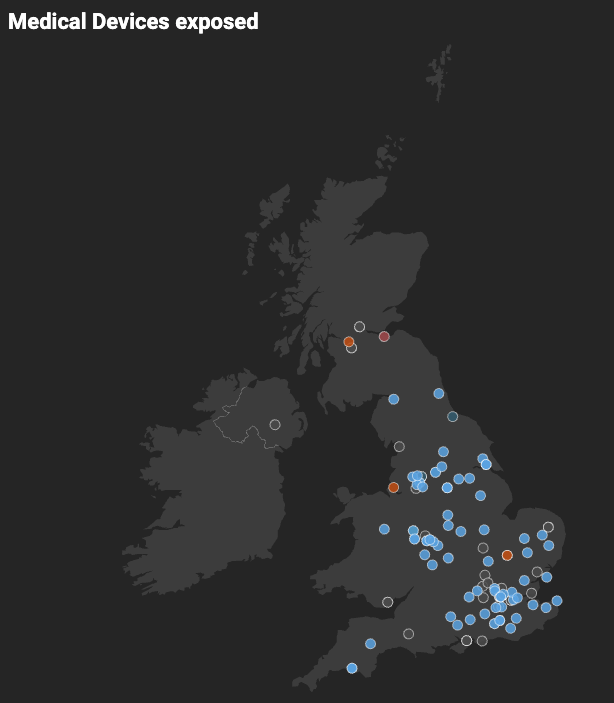
Using Project Sonar, Rapid7’s internet-wide exposure monitoring framework, we identified more than 30 UK-based healthcare systems responding to DICOM-related requests, including services associated with Port 104. The exposure was not limited to that port. Additional PACS and related healthcare systems were observed to be reachable over web ports such as 80 and 443, with more than 15 PACS devices directly accessible from public IP space.
⠀
Figure 2: UK-based exposed Healthcare systems to the Internet.
⠀
This methodology does not exploit systems or access patient records. It confirms whether a service is reachable and actively responding.
For healthcare organizations navigating increased regulatory scrutiny and rising cyber threats, this kind of medical device exposure is unnecessary risk.
The cybersecurity risks of exposed medical imaging systems
When a DICOM server is exposed to the internet, and the risk extends beyond technical misconfiguration, it introduces three primary threat categories:
Patient data exposure and healthcare identity theft
DICOM files typically contain structured metadata fields, which may include:
Patient name.
Date of birth.
Study identifiers.
Referring clinician information.
If a system allows metadata queries without authentication or encryption, those identifiers may be retrievable. Healthcare data retains long-term value because it cannot be reissued in the way payment credentials can.
Medical image manipulation and clinical integrity risks
Imaging workflows depend on trusted transmission between modalities, PACS servers, and diagnostic workstations. Research has shown that medical images can be altered using machine learning techniques under controlled conditions.
Exploitation requires access and technical capability, but exposure beyond intended network boundaries increases the potential attack surface. Clinical confidence depends on assurance that imaging data has not been modified in transit.
Ransomware entry points via PACS and imaging systems
Medical imaging systems like DICOM connect to PACS servers. If an exposed DICOM service provides a foothold, attackers may attempt lateral movement inside the network.
An exposed PACS server can quickly become operational ground zero – delaying procedures, disrupting diagnostics, and impacting patient care. As healthcare continues to face ransomware targeting across the UK and EU, edge systems and externally visible services are often initial access points.
UK healthcare attack surface exposure: DICOM is part of a wider pattern
The exposure of 30+ DICOM systems is concerning. But it is not isolated. A broader review of UK healthcare-associated IP space shows externally visible infrastructure including:
Cisco edge devices.
BigIP appliances.
Check Point firewalls.
Citrix NetScaler instances.
Ivanti Endpoint Manager Mobile.
SSL VPN portals.
Search for NHS registered names and filter on UK/GB:
Table 1: Externally visible technologies identified across UK healthcare-associated IP space.
⠀
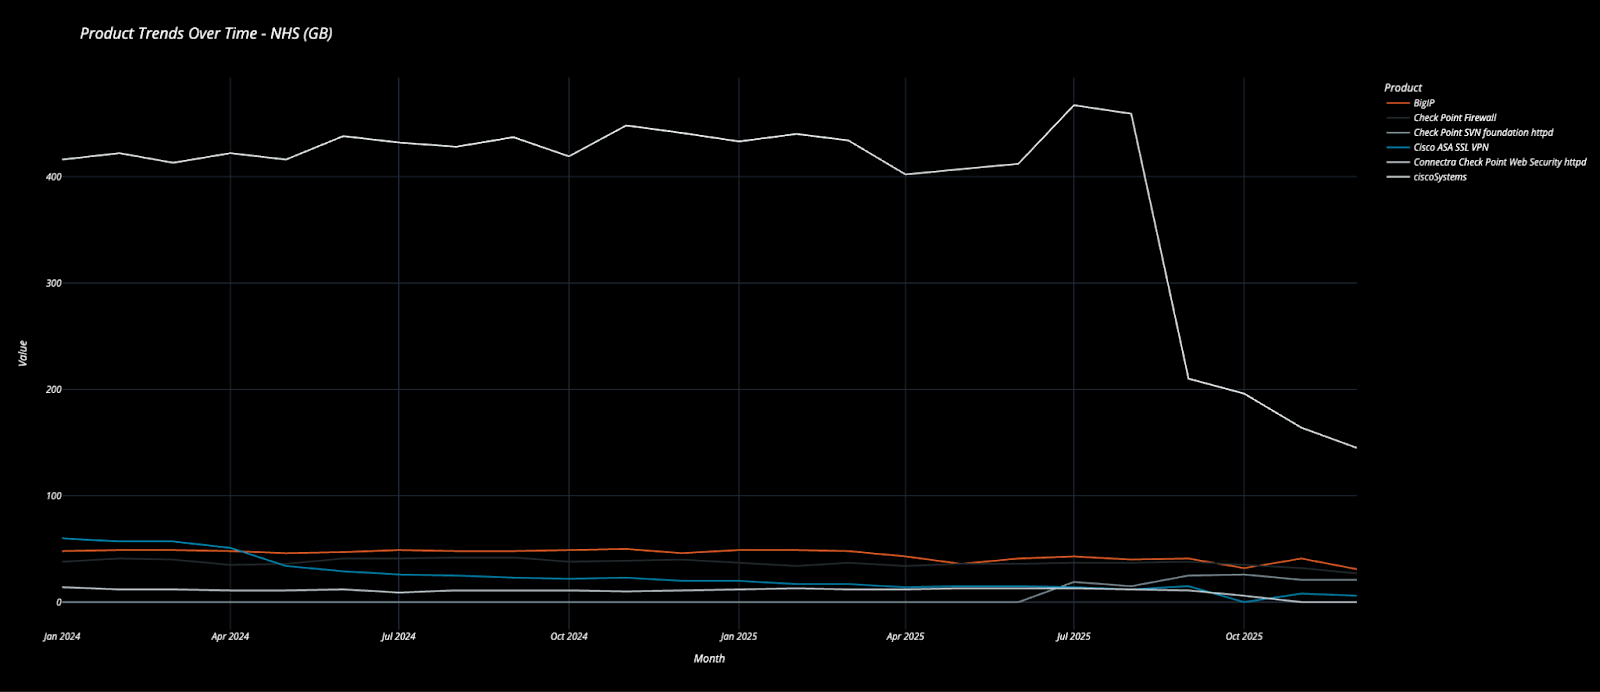
These technologies are standard components of modern IT environments. The concern arises when exposure is unintended, unmonitored, or paired with delayed remediation. Public reporting in 2025 shows that ransomware groups continue to target healthcare following disclosure of vulnerabilities in edge appliances and remote access technologies. In several documented cases, exploitation occurred within days of vulnerability publication.
When more than 30 imaging systems are externally reachable, the underlying issue is unlikely to be a single isolated configuration error. It suggests incomplete visibility into which services are accessible from outside the organisation at any given moment.
⠀
Figure 3: Visibility of selected healthcare technologies over time.
External asset visibility and healthcare IT complexity
Healthcare IT environments evolve incrementally, with legacy protocols remaining operational because imaging equipment has long service lifecycles. This slow evolution can cause complications like:
Vendor default configurations are often inherited from initial deployment.
Cloud services introducing additional infrastructure layers that may not be consistently mapped alongside on-premise systems.
⠀
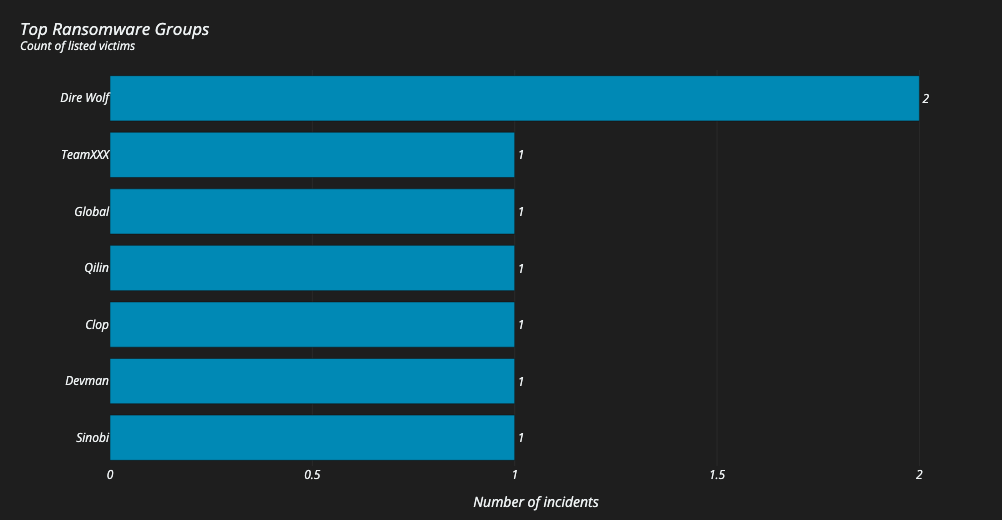
Figure 4: Ransomware groups observed targeting UK/EU healthcare in 2025.
⠀
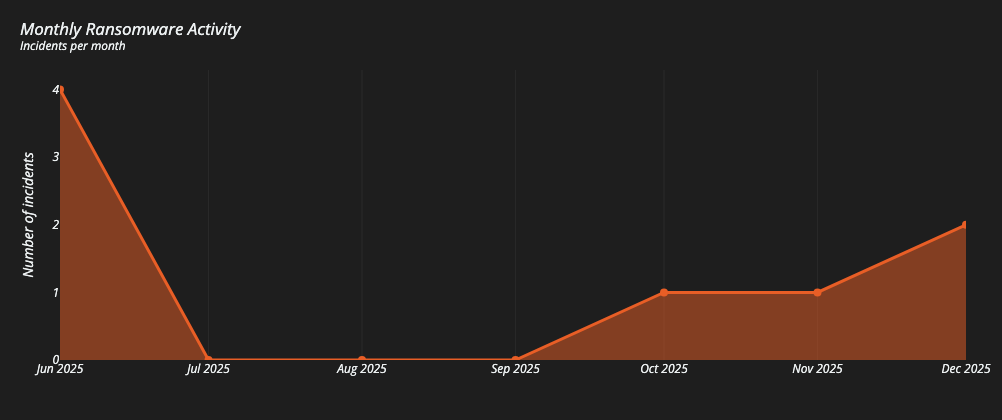
Figure 5: Ransomware group activity observed around UK/EU healthcare in 2025.
Within this context, continuous external visibility becomes challenging. Many organisations do not maintain a real-time inventory of internet-facing services across all owned IP ranges. And so, without deliberate intent, a DICOM server or medical device can become externally reachable., Until specifically identified, the exposure can persist. The lesson?Infrastructure designed for ease of deployment can accumulate risk when oversight is periodic rather than continuous.
How to reduce DICOM and medical device exposure
As ransomware groups accelerate and exploitation windows shrink, it would be easy to frame exposure as oversight. But that diagnosis would miss the point.
The issue is not a lack of cybersecurity awareness within the NHS. It is the structural complexity of modern healthcare IT environments, with legacy protocols continuing to operate alongside newer systems.
Vendor-default configurations are often inherited rather than re-architected.
Third-party integrations expand the digital perimeter beyond the hospital campus.
Remote access services enable flexible care delivery, while cloud adoption accelerates faster than traditional governance models can adapt.
In this kind of environment, many organizations lack continuous visibility into which services are externally exposed at any given moment. If you do not know a medical device or DICOM server is accessible from the internet, you cannot secure it. What was once ‘plug and play’ infrastructure can quietly become ‘plug and prey’.
Securing DICOM servers in healthcare
Organizations reviewing imaging system security should confirm whether Port 104 is accessible from outside trusted networks. Where external access is operationally required, it should be restricted through VPN controls and strong authentication. DICOM traffic should be encrypted where supported.
Additional steps include:
Reviewing firewall rules governing PACS and modality communication.
Conducting periodic external service discovery across owned IP ranges.
Verifying vendor default configurations during deployment and upgrade cycles.
Monitoring newly exposed services following infrastructure or cloud changes.
These measures focus on aligning network exposure with clinical intent. The objective is straightforward: Ensure that imaging systems are reachable only by the parties that need them.
Healthcare cyber resilience starts with visibility
Imaging systems play a central role in diagnosis and care planning, with operational disruption creating immediate clinical consequences.. As regulatory scrutiny of healthcare cybersecurity continues to increase, confirming that DICOM services operate within intended network boundaries is a practical and measurable step toward reducing risk.
The identification of more than 30 exposed systems highlights a visibility gap rather than a failure of awareness. Addressing that gap begins with systematic review of external-facing infrastructure and sustained monitoring over time.
Разводът между Европа и САЩ не само няма да бъде преразгледан, а ще се задълбочава и както изглежда, разделянето на „имуществото“ ще бъде доста по-болезнено от очакваното. Така можем да обобщим изводите от тазгодишната Конференция по сигурността в Мюнхен, проведена от 13 до 15 февруари.
На срещата се потвърди тенденцията, зародила се още в първия мандат на Доналд Тръмп, че най-силният международен съюз в човешката история – геополитическото партньорство между САЩ и Европа, не просто е обезсилен, а Америка и Старият континент все по-често се превръщат в опоненти по редица ключови теми: войната в Украйна, американските апетити към Гренландия, бъдещото управление в ивицата Газа, агресивната американска намеса във вътрешната политика на европейските държави. На конференцията в Мюнхен германският канцлер Фридрих Мерц беше най-директен в оценката си, казвайки , че „световният ред – такъв, какъвто го познаваме, вече не съществува“.
Без Америка като съюзник Европа няма друг избор освен смелостта
В годишния доклад на Мюнхенската конференция по сигурността за 2026 г., озаглавен Under Destruction, се поставят без заобикалки настоящите проблеми на Европа – Старият континент се намира в центъра на една стратегическа преоценка на собствената си роля в условията на ескалираща световна конфронтация, война и загуба на съюзници. В доклада се подчертава, че Европа вече не може да разчита на автоматичните гаранции за сигурност от САЩ – нещо, с което западноевропейците бяха свикнали от края на Втората световна война насам, а източноевропейците – след 90-те години на миналия век.
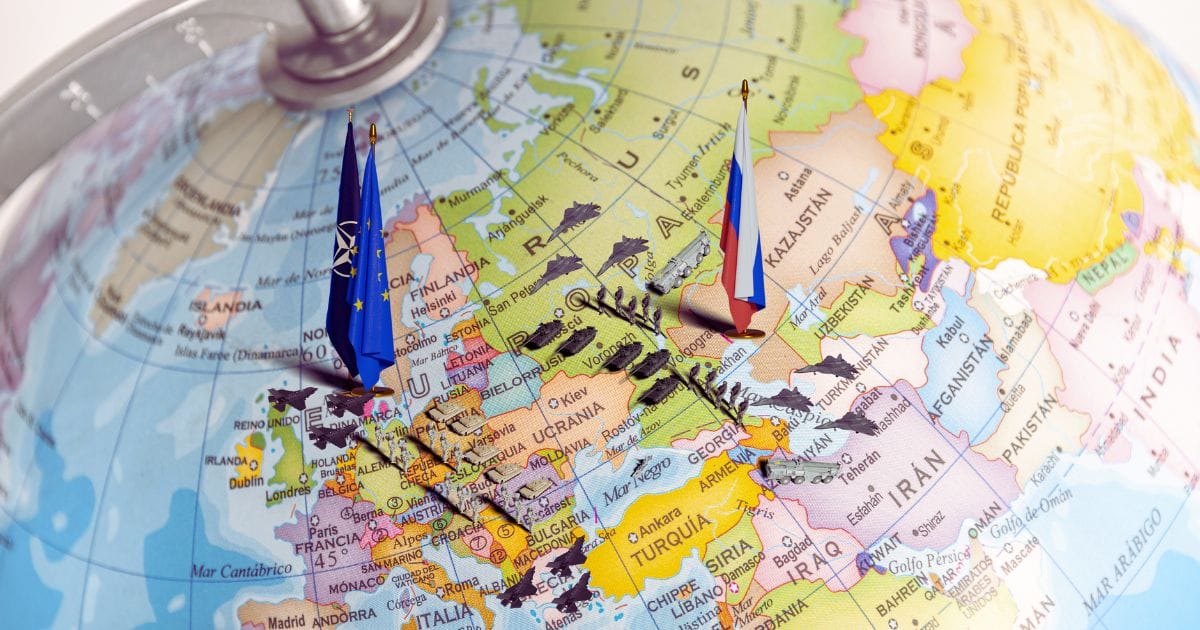
Първата и може би най-важна констатация в главата за Европа е, че продължаващата руска агресия срещу Украйна се простира далеч отвъд бойните полета и подкопава европейската архитектура на сигурност. Това включва разрастващото се влияние върху политическата стабилност на държавите, както и увеличаването на заплахите от военни атаки, кибератаки, дезинформация и други форми на хибридна агресия. Русия е определена като „най-значителната и непосредствена заплаха“ за Европа и НАТО и нейните действия са описани като продължение на разрушаването на приетите през XX век международно право и норми за териториална цялост.
В доклада се подчертава и острата нужда от европейска автономия в сферата на отбраната и от трансформация на ролята на Европа от „консуматор на сигурност“ в „производител на сигурност“. Изрично се заявява, че Европа трябва да развие собствена отбранителна индустрия, да укрепи вътрешното сътрудничество по технологични въпроси като киберсигурност, дронове, системи за противовъздушна отбрана, както и да повиши способностите си за колективно реагиране, без да разчита на американска помощ.
Част от тези промени вече текат с бързи темпове. Украинският опит във войната от 2022 г. насам е изключително ценен, особено що се отнася до бъдещето на военното дело – използването на дронове. Това накара няколко европейски държави да реформират армиите си. Сред тях са три от големите военни сили на континента – Великобритания, Полша и Германия, които вече работят със специалисти в битките с дронове от украинската армия, за да обучат собствените си въоръжени сили чрез използване на опита им. Тези тенденции не са въпрос единствено на военен бюджет, а изискват спешни структурни реформи, координирани приоритети и силна политическа воля, включително навлизане в нови сфери на военно-индустриална интеграция, както и подготвяне на европейските общества за потенциално разширяване на конфликта.
В доклада също така се обръща внимание на вътрешните различия и разделения в Европа: държави като Полша и Германия, с по-високи военни разходи и силна промишлена база, се различават от по-слабо подготвените страни в югозападната част на континента, което подкопава пълната колективна готовност. Тази фрагментация, освен финансова, е политическа и стратегическа, така че се изискват усилия за хармонизиране на политиките и ресурсите, ако Европа иска да играе ефективна роля в собствената си защита и в глобалната сигурност.
Старият континент стои пред исторически избор: бъдеще, в което играе само частична роля в сферата на сигурността, остава зависим от външни гаранции и бързо се превръща в потенциална цел; или предприемане на смели стъпки към същинска автономия – икономическа, технологична и военна. Този избор не е лесен, но според авторите на доклада е неизбежен, ако Европа иска да остане основен фактор в международната политика.
Бордът за мир на Тръмп: Как България се оказа между световните диктатори?
Сякаш като доказателство за разногласието между САЩ и Европа, след приключването на конференцията в Мюнхен американският държавен секретар Марко Рубио пътува до Унгария и Словакия, за да се срещне с Виктор Орбан и Роберт Фицо – най-близките партньори на Русия в ЕС. Ден по-късно във Вашингтон Тръмп свика Борда за мир за първи път. Първоначално замислена като рамка за възстановяване на Газа, организацията разширява целта си, която според самия Тръмп вече включва разрешаване на конфликти в много краища на света.
На срещата присъстваха представители на повече от 40 държави – сред тях имаше пратеници на авторитарни режими, като Беларус, Казахстан, Египет и Саудитска Арабия. Основните европейски съюзници на САЩ обаче не приеха поканата на Тръмп да се присъединят към Борда, в това число Франция, Германия, Великобритания, Испания и Украйна. По-рано тази седмица Ватиканът заяви, че също няма да се присъедини, тъй като смята, че „ООН трябва да управлява тези кризисни ситуации“. Важно е да се отбележи, че Европейската комисия (ЕК) в качеството на наблюдател изпрати собствени представители на срещата. За това действие ЕК получи остри критики от Франция и от групи в Европейския парламент.
На този фон България зае позиция, която я отличи от общата европейска посока и шокира обществото. Правителството в оставка начело с Росен Желязков без никакво предварително обсъждане подписа хартата за участие в Борда за мир, поставяйки страната сред само двете членки на ЕС, които официално подкрепят инициативата на Тръмп. Наред с Унгария, България се оказа в група държави, които демонстрират по-голяма готовност да следват американската линия дори когато тя влиза в противоречие с доминиращата позиция в Брюксел и в големите европейски столици. Този ход на София беше по-скоро очакван, защото у нас от години се води външна политика, която не се съобразява с националните ни интереси, а гледа към големите световни авторитарни режими.
Подписът на Желязков под учредителния документ на Борда предизвика вътрешнополитически и правен спор. Коалицията ПП–ДБ обяви, че настоява да се сезира Конституционният съд, за да провери дали подписаното споразумение съответства на Конституцията, преди то да бъде ратифицирано от Народното събрание. Беше подчертано, че документът е подписан без парламентарен контрол и че трябва да се прецени дали това е допустимо според законодателството. Срещу присъединяването се обявиха също преподаватели в Юридическия факултет на Софийския университет „Св. Климент Охридски“, както и общественици от инициативата „Форум за демократично действие“ (ФДД) .
Хаотичността на решението на кабинета „Желязков“ беше потвърдена от новото служебно правителство. Още с встъпването си в длъжност служебната външна министърка Надежда Нейнски, която е сред основателите на ФДД, обяви, че са налице много резерви и въпросителни относно правния статус на американската инициатива и че самата правна основа на подписания документ засега е неясна.
Конкретната инициатива на Тръмп обаче е само симптом на пълната липса на стратегическа ориентация на България. Докато водещите държави от ЕС се стремят да запазят единна линия и да укрепят общата европейска външна политика, управляващите в София, изглежда, избират външнополитическа дезориентация, която се определя от тесни партийни и олигархични интереси и зависимости, отдалечавайки по този начин страната от европейското ядро. В контекста на споровете в Мюнхен това поведение на София и Будапеща се вписва в по-широката картина на Европа „на различни скорости“ – континент, в който единството по ключови геополитически въпроси вече не може да се приема за даденост.
Европа на две скорости и бъдещето на българската външна политика
Концепцията за „Европа на две скорости“ отново излиза на преден план като възможен отговор на екзистенциалните заплахи, пред които е поставен Старият континент, и в частност Европейският съюз. Според анализатори ЕС изпитва трудности с конкурентоспособността и инвестициите и трябва да навакса технологичното изоставане от САЩ и Китай. В този контекст се обсъжда вариант част от държавите членки – най-интегрираните и икономически най-силните – да напредват по-бързо в определени политики и реформи, а останалите страни да се присъединят по-късно. Така работи например валутният съюз на еврозоната.
Поддръжниците на подобна идея твърдят, че това би направило ЕС по-гъвкав и по-ефективен, като позволи на амбициозните държави да задълбочат интеграцията си без блокиране от страни, които не са готови за същото ниво на ангажимент. По този начин потенциално ще могат да бъдат преодолявани опитите на отделни страни членки, като Унгария например, да злоупотребяват с правото си на вето в полза на противниците на Европа.
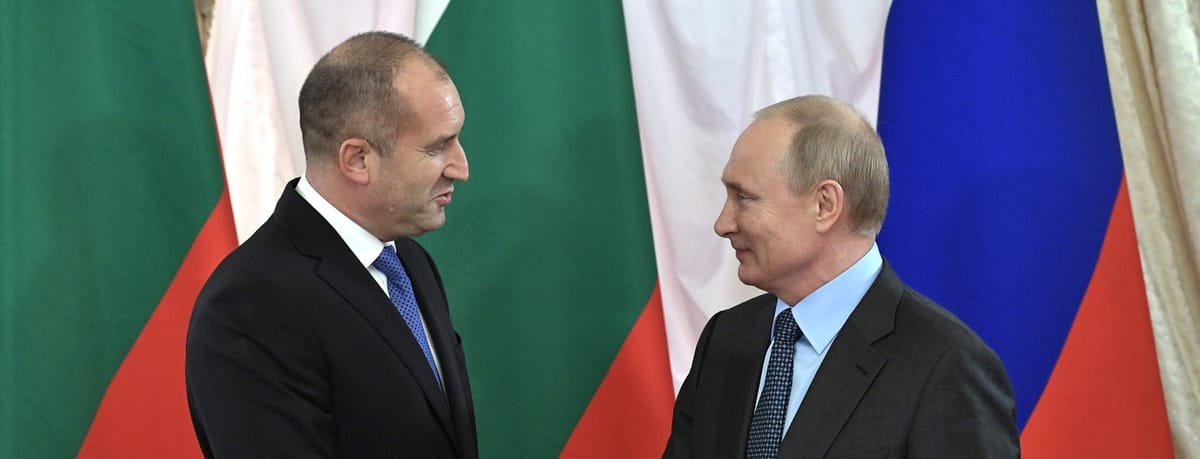
В България темата предизвиква разнопосочни реакции. Известният със симпатиите си към Путин бивш президент Румен Радев изказа мнение, че „Европа на две скорости“ може да задълбочи разделението между държавите и да направи Съюза по-уязвим. Според него подобен модел рискува да оформи ядро и периферия, което би отслабило солидарността и равнопоставеността между членовете на ЕС. Различна позиция изразява евродепутатът Радан Кънев, който подчертава, че България трябва да се стреми да бъде част от „Европа на първа скорост“. Според него страната не бива да се страхува от по-дълбока интеграция, а трябва активно да участва във важни европейски политики, включително в областта на икономиката, енергетиката и общата отбрана. В този смисъл концепцията следва да се разглежда не като заплаха, а като стимул България да повиши своята конкурентоспособност и институционална готовност.
On February 12, Yeoreum Yun posted a suggestion
for an improvement to the security of the kernel’s BPF implementation: use
memory protection keys to prevent unauthorized access to memory by BPF
programs.
Yun wanted to put the topic on the list for discussion at the Linux
Storage, Filesystem, Memory Management, and BPF Summit in May, but the
lack of engagement makes that unlikely. They also have a patch set implementing
some of the proposed changes, but has not yet shared that with the mailing list.
Yun’s proposal does not seem likely to be accepted in its
current form, but the kernel has
added hardware-based hardening options in the
past, sometimes after substantial discussion.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.