This blog post discusses the AWS Lambda as orchestrator anti-pattern and how to redesign serverless solutions using AWS Step Functions with native integrations.
Step Functions is a serverless workflow service that you can use to build distributed applications, automate processes, orchestrate microservices, and create data and machine learning (ML) pipelines. Step Functions provides native integrations with over 200 AWS services in addition to external third-party APIs. You can use these integrations to deploy production-ready solutions with less effort, reducing code complexity, improving long-term maintainability, and minimizing technical debt when operating at scale.
The Lambda as orchestrator anti-pattern
Let’s examine a common anti-pattern: using a Lambda function as an orchestrator for message distribution across multiple channels. Consider this real-world scenario where a system needs to send notifications through SMS or email channels based on user preferences, as shown in the following diagram.
Here’s how it typically starts—with a Lambda function acting as an orchestrator:
import boto3
import json
# Initialize Lambda client
# You can specify region if needed: boto3.client('lambda', region_name='us-east-1')
lambda_client = boto3.client('lambda')
def lambda_handler(event, context):
    try:
        # Parse the incoming event
        body = json.loads(event['body'])

        # Validate required fields
        if 'channel' not in body:
            return {
                'statusCode': 400,
                'body': json.dumps('Missing channel parameter')
            }

        if 'message' not in body:
            return {
                'statusCode': 400,
                'body': json.dumps('Missing message content')
            }

        if body['channel'] == 'both':
            # Invoke SMS Lambda function
            lambda_client.invoke(
                FunctionName='send-sns',
                InvocationType='Event',
                Payload=json.dumps(body)
            )

            # Invoke Email Lambda function
            lambda_client.invoke(
                FunctionName='send-email',
                InvocationType='Event',
                Payload=json.dumps(body)
            )
        else:
            # Validate channel value
            if body['channel'] not in ['sms', 'email']:
                return {
                    'statusCode': 400,
                    'body': json.dumps('Invalid channel specified')
                }

            # Invoke function based on specified channel
            function_name = 'send-sns' if body['channel'] == 'sms' else 'send-email'
            lambda_client.invoke(
                FunctionName=function_name,
                InvocationType='Event',
                Payload=json.dumps(body)
            )

        return {
            'statusCode': 200,
            'body': json.dumps('Messages sent successfully')
        }

    except json.JSONDecodeError:
        return {
            'statusCode': 400,
            'body': json.dumps('Invalid JSON in request body')
        }
    except Exception as e:
        return {
            'statusCode': 500,
            'body': json.dumps(f'Error: {str(e)}')
        }
This approach has the following problems:
Complex error handling: The orchestrator needs to manage errors from multiple function invocations.
Tight coupling: Functions are directly dependent on each other.
Limited execution time: The orchestrator Lambda function continues running while sub Lambda functions execute. This could lead to the orchestrator Lambda function timing out.
Idle resources: Because the orchestrator Lambda function is sitting idle waiting for returns from other Lambda functions, in this case, the user is now paying for idle resources.
Rearchitecting with Step Functions
You can rebuild the logic using Step Functions and Amazon States Language to replace the Lambda orchestrator function. You can use the Choice state in Amazon States Language to define logical conditions to follow a specific path. This approach reduces code maintenance complexity because you define the conditions using Amazon States Language. You can also use it to to extend the functionality with minimal changes to the codebase.
The following Step Functions workflow diagram shows the rearchitected version of the previous Orchestrator Lambda function:
The following Amazon State Language represents the workflow:
Visual workflow: The execution flow is visible and maintainable through the AWS Management Console
Built-in error handling: Retry policies and error states can be defined declaratively
Parallel execution: The Parallel state handles multiple channel delivery efficiently
Simplified logic: The Choice state replaces complex if-else statements
Centralized data flow: Input and output are managed consistently across states
Enhanced workflow duration capabilities: Step Functions Standard workflows support executions that run for up to one year, compared to the 15-minute maximum execution time for Lambda functions
Comparing Lambda function as orchestrator to Step Functions
The summary of different features implemented on Lambda function as orchestrator and Step Functions is reflected in the following table:
Feature
Lambda function as orchestrator
Step Functions
Orchestration logic
Implemented in Python with nested if-else statements.
Defined declaratively using the Choice state
Multi-channel delivery
Sequential function invocations. Parallel execution using function’s logic.
Parallel execution using the Parallel state
Service integration
Requires SDK calls or separate Lambda functions.
Direct integration with AWS services (Amazon SNS, DynamoDB)
Error handling
Custom try-except blocks in Python.
Built-in error states and retry policies
Data persistance
Custom code to interact with DynamoDB.
Native DynamoDB integration with putItem task
Metrics logging
Custom code to call CloudWatch.
CloudWatch Metrics SDK integration
Implementation considerations
Review the following considerations when re-architecting a Lambda function orchestrator to Step Functions:
State machine type: Choose between Standard (up to 1 year runtime) and Express (up to 5 minutes) workflows based on your needs.
Input/output management: Parameters manipulation reduces the development effort and give flexible alternatives to implement the workflow:
Parameters: Selects specific input fields to pass to the next state
ResultSelector: Filters the state response to include only relevant fields
ResultPath: Stores the processed result in a specific path of the state input
OutputPath: Determines what data passes to the next state A code snippet for these features is:
Error handling: Implement retry policies and catch errors at both the task and state machine levels.
Monitoring: Set up CloudWatch logs and metrics for your state machine to track executions and performance.
Benefits of using Step Functions
Using Step Functions for rearchitecting scenarios bring the following benefits:
Reduced code complexity: The business logic is now defined in Amazon States Language rather than distributed across multiple Lambda functions.
Improved maintainability: Developers can make workflow changes by modifying the Amazon States Language, often modifying several Lambda functions.
Native AWS service integrations: Step Functions offers direct integrations with over 200 AWS services, which you can use to connect and coordinate AWS resources without writing custom integration code.
Cost optimization: By using direct service integrations, there are fewer Lambda invocations and reduced costs.
Long-running processes: Step Functions can manage workflows that run for up to a year, beyond the 15-minute limit for Lambda functions.
Conclusion
Rearchitecting Lambda-based applications with Step Functions can significantly improve maintainability, scalability, and operational efficiency. By moving orchestration logic into Step Functions and using its native service integrations, you can create more robust and manageable serverless applications.
While this post focused on a message distribution workflow, the principles apply to many serverless architectures. As you develop your applications, consider how Step Functions can help you build more resilient and scalable solutions.
To learn more about serverless architectures visit Serverless Land.
Recent security research has highlighted the importance of CI/CD pipeline configurations, as documented in AWS Security Bulletin AWS-2025-016. This post pulls together existing guidance and recommendations into one guide.
Continuous integration and continuous deployment (CI/CD) practices help development teams deliver software efficiently and reliably. AWS CodeBuild provides managed build services that integrate with source code repositories like GitHub, GitLab, and other Source Control Management (SCM) systems. While this guide uses GitHub examples, the security principles and webhook configuration approaches apply to other supported source control systems.
However, certain configurations require careful attention. We strongly recommend that you do not use automatic pull request builds from untrusted repository contributors without proper security controls and a clear understanding of your threat model. This configuration allows untrusted code to execute in your build environment with access to repository credentials and environment variables. Webhook configurations determine which repository events trigger builds and what code gets executed during the build process. Understanding these configurations is essential for maintaining appropriate security boundaries while preserving the automation benefits that make CI/CD valuable.
Security teams and DevOps engineers can use these practical approaches to configure AWS CodeBuild to meet their security goals while maintaining development velocity. We’ll explore webhook configurations, trust boundaries, and implementation strategies that emphasize threat model assessment, least-privilege access, and proactive monitoring of your pipeline configurations.
Security of the pipeline implications
Under the shared responsibility model, while AWS manages the security of the underlying AWS CodeBuild infrastructure, customers are responsible for securing their pipeline configurations, access controls, and the code that runs within their build environments. This shared responsibility is critical when considering the security of the pipeline itself.
When AWS CodeBuild processes pull requests automatically, it builds the code in an environment with access to repository credentials, environment variables, and potentially sensitive information. This creates specific security of the pipeline considerations:
Repository access: AWS CodeBuild projects require repository credentials to read source code and create webhooks. These credentials provide specific permissions that vary based on your configuration.
Build execution: The build process runs the retrieved source code, which may include build scripts, dependency definitions, or test files from pull requests.
Build environment: AWS CodeBuild environments may have access to environment variables, AWS credentials, or other configuration data needed for the build process.
Establishing trust boundaries
Effective security of the pipeline starts with clearly defining trust boundaries for different types of code contributions:
Internal contributors: Team members with repository write access who have been verified through your organization’s access management processes.
External contributors: Contributors from outside your organization who submit pull requests from forked repositories.
Automated processing: Code that runs without manual review as part of the build process.
These trust boundaries form the foundation for threat modeling your specific environment. Internal and trusted environments can often rely more heavily on automation with contributor filtering and least-privilege controls. Public and open source projects require more stringent controls due to the inherent risks of processing untrusted contributions – these environments benefit from stricter webhook filtering, comprehensive approval gates, or the self-hosted GitHub Actions runner approach discussed later.
The key principle is finding the appropriate balance between security controls and development velocity based on your specific risk profile and contributor trust levels. With these considerations in mind, let’s examine how to assess and configure your current AWS CodeBuild webhook settings.
Configuring secure webhooks
Webhooks represent the preferred mechanism by which external events trigger AWS CodeBuild processes. When properly configured, webhooks provide a powerful and efficient way to automate your build processes in response to repository changes. However, improper webhook configuration can create security vulnerabilities by allowing untrusted code to execute in privileged environments.The security of your webhook configuration depends on understanding exactly which events trigger builds, what level of access those builds have, and what code gets executed during the build process. This section provides a comprehensive approach to authoring, assessing, configuring, and maintaining secure webhook configurations.
Assessing current webhook configurations
Begin by reviewing your existing AWS CodeBuild projects to understand their current webhook configurations. The following AWS CLI commands provide a systematic approach to gathering this information:
# List all CodeBuild projects in your region
aws codebuild list-projects --region us-west-2

# Retrieve detailed configuration for analysis
aws codebuild batch-get-projects --region us-west-2 \
  --names $(aws codebuild list-projects --region us-west-2 \
  --query 'projects[*]' --output text | tr '\n' ' ')
When you run these commands, pay particular attention to the webhook section in the output. This section contains the filterGroups configuration, which determines exactly which repository events trigger builds.
Now that you understand how to review your current setup, let’s examine common configuration patterns and their security implications.
Webhook configuration patterns
Understanding common webhook configuration patterns helps you quickly identify potential security concerns and implement appropriate improvements. The following patterns represent different approaches to webhook configuration, each with specific security implications.
Note: These patterns are not recommended for use and are shown here to help you identify configurations that may need attention.
This configuration allows contributors who can create a pull request to trigger code execution in your build environment. We strongly recommend that you do not use automatic pull request builds from untrusted repository contributors.
Configuration requiring immediate review – No event filtering
Without filtering, this configuration can trigger builds for a wide variety of repository events.
Recommended secure webhook configurations
The following configurations represent security best practices that balance automation benefits with appropriate security controls. These patterns help to reduce security risks while maintaining the development velocity that makes CI/CD valuable.
Push-based builds (Recommended for most use cases)
Push-based builds make sure that only users with repository write access can trigger builds, which means contributors have already been vetted through your repository’s access control mechanisms.
Organizations that rely heavily on external open-source contributions may find this approach too restrictive. For example, a popular open-source project that receives dozens of pull requests daily from external contributors would need to manually merge each contribution before builds can run, significantly slowing down the contribution review process. In such cases, contributor-filtered builds or the self-hosted GitHub Actions runner approach may be more appropriate.
Contributor-filtered builds (Recommended for trusted contributors only)
This configuration allows pull request builds from specific, trusted contributors.
Important: Filtering applies to the GitHub account ID, not repository ownership. Contributors working from forked repositories can still introduce untrusted code that executes in your build environment.
Before implementing these configurations in your environment, consider these key factors that will help facilitate a smooth transition.
Webhook configuration implementation steps
While implementing the webhook security measures below, consider these broader practices:
Threat modeling: Assess your specific risk profile before selecting approaches.
Infrastructure as code: Use Infrastructure as Code (IaC) tools for production implementations.
Gradual implementation: Implement changes incrementally with observation periods.
Testing and rollback: Validate changes in non-production environments first.
The following implementation approach moves from most restrictive to more automated configurations. Choose the approach that best fits your organization’s risk tolerance and operational requirements. This three-step process moves from the most restrictive approach to more automated configurations while maintaining security controls. Each step builds upon the previous one, creating layers of security that work together to protect your pipeline.
Note: The following examples use the AWS CLI for demonstration purposes. Similar configuration steps can be performed using the AWS Management Console through the AWS CodeBuild project settings.
Step 1: Configure push-only builds
Push-based builds help make sure that only verified contributors can trigger builds. This approach is more secure, because contributors must already be vetted through your repository’s access control mechanisms before they can push code. Configure your webhook to trigger only on push events:
Branch-based filtering adds an additional layer of security by making sure that builds are triggered only for changes to specific branches. This approach recognizes that not all branches in a repository have the same security requirements or risk profiles.
For example, changes to main or production branches typically require more stringent security controls than changes to feature or development branches. By implementing branch-based filtering, you can apply appropriate security measures based on the criticality and exposure of different branches.
Contributor filtering can be used to manage pull request builds by allowing automation for trusted contributors while requiring manual review for others. This approach recognizes that different contributors represent different risk profiles and should be treated accordingly.
The first step in implementing contributor filtering is identifying the GitHub user IDs of your trusted contributors.
Retrieve GitHub user IDs for trusted contributors:
Important: Contributor allowlists require ongoing maintenance as team membership changes. Consider using Infrastructure as Code templates like the Cloudformation examples to manage webhook configurations and contributor lists in version control.
Webhook filtering provides the first layer of security by controlling which events trigger builds. However, comprehensive pipeline security requires additional controls around the permissions and credentials available to those builds once they execute. The following section covers how to implement defense-in-depth security through proper access controls and credential management.
Access control and credential management
This section covers specific approaches to limit the permissions available to build processes, scope repository access tokens appropriately, and create isolated environments that help contain potential security issues. These practices work together to implement defense-in-depth security while maintaining the operational benefits of automated CI/CD workflows.
Implementing least-privilege access
AWS CodeBuild projects require IAM service roles to access AWS resources during the build process. The principle of least privilege dictates that each role should have only the minimum permissions necessary to perform its intended function. By creating separate, purpose-built IAM roles for different types of builds, you can help reduce the potential impact of unauthorized access to build environments.
The following examples demonstrate how to structure minimal IAM roles for different build scenarios. These examples serve as starting points that you should customize based on your specific requirements, adding only the permissions your builds actually need.
Service role configuration
Create minimal IAM roles that provide only the permissions required for specific build types:
Leveraging IAM Access Analyzer for CodeBuild security
AWS IAM Access Analyzer can generate least-privilege policies for your AWS CodeBuild service roles based on actual CloudTrail activity from your build executions. This eliminates guesswork by analyzing the specific AWS API calls your builds make, rather than requiring you to predict what permissions might be needed.
After running your CodeBuild projects for a representative period, use Access Analyzer’s policy generation feature to create refined policies. This approach proves particularly valuable for complex build processes where the required permissions might not be immediately obvious.
When processing external contributions, the principle of least privilege becomes important for repository access tokens. If an unauthorized user gains access to a token through an untrusted build, properly scoped tokens limit the potential impact to only the permissions necessary for the build process.
Configure fine-grained GitHub Personal Access Tokens with minimal permissions to help reduce this risk. Even if accessed inappropriately, a properly scoped token can only read source code (already accessible through the PR) and write status messages – it cannot push code, modify repository settings, or access other repositories.
The following permissions represent the minimum required access for processing external pull requests, demonstrating how to limit token scope to only essential operations:
contents:read – Read-only access to repository source code (already accessible through the PR)
statuses:write – Write commit status messages only (cannot modify code or settings)
metadata:read – Access basic repository information (name, description, public status)
Important: Use fine-grained personal access tokens restricted to the target repository only. Otherwise, this could allow access to other repositories beyond what is necessary for the build process.
This scoped approach ensures that even if a token is accessed inappropriately, the potential impact is limited to reading already-accessible information and writing status messages. The token cannot push code, modify repository settings, create webhooks, or access other repositories.
Credential storage and rotation
The following examples demonstrate how to securely store and reference these tokens using AWS Secrets Manager. AWS Secrets Manager provides automatic rotation capabilities, encryption at rest and in transit, and fine-grained access controls that help prevent tokens from being exposed in build logs or configuration files. This approach also enables centralized token management across multiple CodeBuild projects while maintaining audit trails of token access.
The centralized storage enables credential rotation capabilities, helping to minimize the window of exposure compared to hardcoded tokens that would require infrastructure updates to rotate.
Build environment isolation
Establishing proper build environment security controls helps maintain pipeline integrity. The foundation of this approach involves implementing separation between test and release builds, which helps prevent credential escalation and limits the scope of potential unauthorized access.
Network isolation represents another layer of protection. Configure VPC settings specifically for builds that process external code by creating dedicated security groups with carefully restricted outbound access. These security groups should permit only necessary connections, such as HTTPS traffic for downloading legitimate dependencies, while blocking unnecessary network access that could be exploited by untrusted code.
Update your AWS CodeBuild projects to leverage this network isolation through proper VPC configuration, including specified subnets and the restricted security groups you’ve established.
Multi-stage pipeline security with human review gates
Implementing security controls across multiple pipeline stages helps provide proper validation and approval processes, especially when processing external contributions. This approach combines automated scanning with human oversight to identify issues before they reach production.
Code inspection integration
Configure your build specification to automatically run security tools like Automated Security Helper during the build process. These tools scan for code security issues and dependency problems, generating detailed reports for review.
Structure the build to continue execution even when issues are found, allowing all scans to complete while automatically failing builds that contain security problems requiring attention. Store all scan artifacts to provide security teams with detailed information for approval decisions.
Manual approval gates
After code passes automated security scans, configure manual approval gates to involve human reviewers for final validation. This helps provide appropriate human review before proceeding to sensitive environments.
The access control and credential management practices outlined in this section provide specific, actionable approaches to implementing defense-in-depth security for AWS CodeBuild pipelines. These controls work together to create multiple layers of protection while maintaining the operational benefits that make CI/CD automation valuable.
Alternative approach – Self-hosted GitHub Actions runners
AWS CodeBuild’s self-hosted GitHub Actions runner capability addresses the configuration issues described in this guide by isolating repository credentials from the build environment and using GitHub Actions’ execution framework instead of AWS CodeBuild webhook processing.
For organizations that need to process external contributions automatically, configure runners with proper access controls, use ephemeral runners to minimize persistent access, and apply standard security practices for runner management.
The security controls outlined in previous sections provide protection at build time, but comprehensive defense-in-depth security requires ongoing visibility into your pipeline activities and configuration changes. Monitoring and compliance tracking serve as the final layer of your security framework, helping you detect configuration drift, audit access patterns, and maintain security posture over time.
AWS CloudTrail provides detailed logging of API calls made to AWS services, including AWS CodeBuild. Enable CloudTrail logging to create a comprehensive audit trail of all build-related activities in your environment.
AWS Config tracks AWS CodeBuild project configurations over time, providing an inventory of projects and a complete history of configuration changes. This includes webhook modifications, resource relationships, and compliance tracking across your environment. Configure AWS Config to monitor AWS CodeBuild projects and receive notifications when security-critical configurations like webhook filters are modified. For more information, see the AWS Config sample with CodeBuild documentation.
Conclusion
Implementing defense-in-depth security for AWS CodeBuild pipelines requires layered controls that address different security considerations. The most effective approach combines webhook filtering, access controls, credential management, and monitoring to provide comprehensive protection. By implementing these layered practices outlined in this guide, you can maintain development velocity while establishing robust pipeline security. Key principles to remember:
Assess your threat model first – different projects require different security approaches
Establish clear trust boundaries between different types of contributors
Use webhook filtering to control when builds are triggered
Implement least-privilege access for build environments
Monitor and audit configurations regularly using AWS Config and CloudTrail
Store secrets in AWS Secrets Manager or SSM Parameter Store and enable rotation
AWS CodeBuild provides the flexibility to implement these security measures while maintaining the operational benefits that make pipelines valuable. Apply the configurations and mitigations in this guide based on your specific risk profile and operational requirements. Regular review and updates of your configurations will help your pipelines remain secure as your organization’s needs evolve.
Stay tuned for additional practical guides for implementing CI/CD security best practices. If you have questions or feedback about this post, including suggestions for topics that would help you most, start a new thread on re:Post : Begimher or contact AWS Support.
As a developer who has embraced the power of the Model Context Protocol (MCP)to enhance my workflows, I’m thrilled to see the addition of custom agents in the Amazon Q Developer CLI. This new feature takes the capabilities I’ve come to rely on to a whole new level, allowing me to seamlessly manage different development contexts and easily switch between them.
In my previous post, I discussed how MCP servers have revolutionized the way I interact with AWS services, databases, and other essential tools. MCP integration in Amazon Q Developer allows me to query my database schemas, automate infrastructure deployments, and so much more. However, as I started juggling multiple projects, each with their own unique tech stacks and requirements, I found myself needing a more structured approach to managing these diverse development environments.
Enter custom agents. With this new feature, I can now create and use a custom agent by bringing together specific tools, prompt, context and tool permissions for tasks appropriate for the stage of development. In this post I will explain how to configure a cusom agent for front-end and back-end development. Allowing me to easily optimize Amazon Q Developer for each task.
Background
Imagine that I am working on a multi-tier web application. The application has a React front-end written in Typescript and a FastAPI back-end written in Python. In addition to me, the team includes a designer that uses Figma, and the database administrator that manages a PostgreSQL database. There are subtle differences in how I communicate with the designer and the database administrator. For example, when I discuss a “table” with the designer, I’m likely referring to an HTML table and how the page is structured. However, when I discuss a table with the database administrator, I’m likely talking about a SQL table and how data is stored.
In the past, I had both the Figma Dev Mode MCP server and Amazon Aurora PostgreSQL MCP server configured in my environment. While this allowed me to easily work on either the front-end or back-end code, it introduced some challenges. If I asked Amazon Q Developer “how many tables do I have?” Amazon Q Developer would have to guess if I was talking about HTML tables or SQL tables. If the question is about HTML, it should use the Figma server. If the question is about SQL, it should use the Aurora server. This is not a technical limitation, it’s a language limitation. Just as I have to adjust my assumptions to talk with the designer and database administrator, Amazon Q Developer has to make the same adjustments.
Enter Amazon Q Developer CLI custom agents. Custom agents allow me to optimize Q Developer’s configuration for each scenario. Let’s walk through my front-end and back-end configuration to understand the impact.
Front-end agent
My front-end custom agent is optimized for front-end web development using React and Figma. The following code example is the configuration for my front-end agent stored in ~/.aws/amazonq/agents/front-end.json. Let’s discuss the major sections of the configuration.
mcpServers – Here I have configured the Figma Dev Mode MCP Server. This simply communicates with the Figma Web Design App installed locally. Note that this replaces the MCP configuration that was stored in ~/.aws/amazonq/mcp.json
tools and allowedTools – These two sections are related, so I will discuss them together. tools defines the tools are available to Amazon Q Developer while allowedTools defines which tools are trusted. In other words, Q Developer is able to use all configured tools, and it does not have to ask my permission to use fs_read, fs_write, and @Figma. @Figma allows Amazon Q Developer to use all Figma tools without asking for permission. More on this in the next section.
resources – Here I have configured the files that should be added to the context. I have included the README.md (stored in the project folder) and my own preferences for React (stored in my profile). You can read more in the context management section of the user guide.
hooks – In addition to the resources, I have also included a hook. This hook will run a command and inject it into the context at runtime. In the example, I am adding the current git status. You can read more in the context hooks section of the user guide.
{
  "description": "Optimized for front-end web development using React and Figma",
  "mcpServers": {
    "Figma": {
      "command": "npx",
      "args": [
        "mcp-remote",
        "http://127.0.0.1:3845/sse"
      ]
    }
  },
  "tools": ["*"],
  "allowedTools": [
    "fs_read",
    "fs_write",
    "report_issues",
    "@Figma"
  ],
  "resources": [
    "file://README.md",
    "file://~/.aws/amazonq/react-preferences.md"
  ],
  "hooks": {
    "agentSpawn": [
      {
        "command": "git status"
      }
    ]
  }
}
Back-end agent
My back-end custom agent is optimized for back-end development with Python and PostgreSQL. The following code example is the configuration for my back-end agent stored in ~/.aws/amazonq/agents/back-end.json. Rather than describing the sections, as I did earlier, I will focus on the differences between the front-end and back-end.
mcpServers – Here I have configured the Amazon Aurora PostgreSQL MCP Server. This allows Amazon Q Developer to query my dev database to learn about the schema. Notice that I have configured a read-only connection to ensure that I don’t accidentally update the database.
tools and allowedTools – Once again, I have enabled Amazon Q Developer to use all tools. However, notice that I am more restrictive about what tools are trusted. Amazon Q Developer will need to ask permission to use fs_write or @PostgreSQL/run_query. Notice that I can allow the entire MCP server as I did with Figma or specific tools as I did here.
resources – Again, I have included the README.md (stored in the project folder) and my own preferences for Python and SQL (both stored in my profile). Note that I can also use glob patterns here. For example, file://.amazonq/rules/**/*.md would include the rules created by the Amazon Q Developer IDE plugins.
hooks – Finally, I have also included the hook for the front-end and back-end. However, I could have included project specific options such as npm run for the front-end and pip freeze for the back-end.
The real power of agents becomes evident when I need to switch between these different development contexts. I can now simply run q chat --agent front-end when I am working on React and Figma or q chat --agent back-end when I am working with Python and SQL. Amazon Q Developer will configure the correct agent with all my preferences.
In the following image, you can see the configuration in the Amazon Q Developer CLI. Notice that the front-end agent has an additional tool called Figma while the back-end agent has an additional tool called PostgreSQL. In addition, the front-end agent trusts fs_write and all of the Figma tools while the back-end agent will ask permission to use fs_write and only trusts one of the two PostgreSQL tools.
Similarly, let’s look at the context configuration in both the front-end and back-end agents. In the following image, I have included my React preferences for front-end development, and both Python and SQL preferences for back-end development.
As you can see, custom agents allow me to optimize the Amazon Q Developer CLI for each task. Of course, front-end and back-end agents are just an example. You might have a developer and testing agents, data science and analytics agents, etc. Custom agents allow you to tailor the configuration to most any task.
Conclusion
Amazon Q Developer CLI custom agents represent a significant improvement in managing complex development environments. By allowing developers to seamlessly switch between different contexts, they eliminate the cognitive overhead of manually reconfiguring tools and permissions for different tasks. Ready to streamline your development workflow? Get started with Amazon Q Developer today.
As introduced in Part 1 of this series, implementing secure file sharing solutions in AWS requires a comprehensive understanding of your organization’s needs and constraints. Before selecting a specific solution, organizations must evaluate five fundamental areas: access patterns and scale, technical requirements, security and compliance, operational requirements, and business constraints. These areas cover everything from how files will be shared and what protocols are needed, to security measures, day-to-day operations, and business limitations.
See Part 1 of this series for detailed information about each of these fundamental areas and their specific considerations. Part 1 also covers solutions including AWS Transfer Family, Transfer Family web apps, and Amazon Simple Storage Service (Amazon S3) pre-signed URLs. This part continues our analysis with additional AWS file sharing solutions to help you make an informed decision based on your specific requirements.
Solutions
Let’s start by looking at the various file sharing mechanisms that AWS supports. The following table identifies the key AWS services needed for each solution, describes the security and cost implications of the solutions, and describes their complexity and protocol support capabilities.
Solution
AWS services
Security features
Cost*
Region control
CloudFront signed URLs
CloudFront, Amazon S3, and Lambda
Optional edge security using AWS Lambda@Edge, WAF integration, SSL/TLS, geo restrictions, and AWS Shield Standard (included automatically)
Content delivery network (CDN) costs, request pricing, and data transfer fees
Global service by design; origin can be AWS Region-specific
Amazon VPC endpoint service
AWS PrivateLink, Amazon VPC, and Network Load Balancer (NLB)
Complete network isolation, private connectivity, and multi-layer security
Endpoint hourly charges, NLB costs, and data processing fees
Service endpoints are strictly Region-specific; must create endpoints in each Region where access is needed
Data transfer fees apply based on standard S3 rates
Amazon VPC endpoint charges apply when using VPC endpoints with access points
Access points are Region-specific
Each access point is created in the same Region as its S3 bucket
Cross-Region access requires separate access points in each Region
VPC-specific access points are limited to the VPC’s Region
The following table shows the solutions described in Part 1.
Solution
AWS services
Security features
Cost*
Region control
AWS Transfer Family
Transfer Family, Amazon S3, API Gateway, and Lambda
Managed security, encryption in transit and at rest, IAM integration, and custom authentication
$0.30 per hour per protocol, data transfer fees, and storage costs
Can deploy to specific AWS Regions, can only transfer files to and from S3 buckets in the same Region
Transfer Family web apps
Transfer Family, S3, and CloudFront
Browser-based access, IAM Identity Center integration, and S3 Access Grants
Pay-per-file operation, CloudFront costs, and storage costs
Uses CloudFront (global) for web access, but backend components can be Region-specific
Amazon S3 pre-signed URLs
S3
Time-limited URLs, IAM controls for URL generation, and HTTPS
S3 request and data transfer fees
Can be restricted to specific Regions
Serverless application with Amazon S3 presigned URLs
S3, Lambda, and API Gateway
Time-limited URLs, HTTPS, IAM controls, customizable authentication
Pay per request and minimal infrastructure cost
Components can be Region-specific
* Pricing information provided is based on AWS service rates at the time of publication and is intended as an estimation only. Additional costs may be incurred depending on your specific implementation and usage patterns. For the most current and accurate pricing details, please consult the official AWS pricing pages for each service mentioned.
Let’s examine each of the solutions in detail. Part 1 talked about AWS Transfer Family, Transfer Family web apps, and Amazon S3 pre-signed URLs. Here in Part 2, we explain the remaining solutions to help you make the right choice for your use case.
CloudFront signed URLs with Amazon S3
Amazon CloudFront signed URLs combine Amazon S3 storage with the global edge network of CloudFront to deliver files securely with lower latency.
CloudFront edge locations cache content geographically closer to users, which usually reduces latency and gives better performance for users. CloudFront also reduces the number of origin requests to Amazon S3. CloudFront integration with AWS Shield and AWS WAF provides options for additional security layers, helping to protect against DDoS events and unintended requests. You can use custom domains with AWS-provided or your own SSL/TLS certificates managed through AWS Certificate Manager (ACM), helping to facilitate secure connections from users to edge locations.
When a user requests a file, the system generates a signed URL using either a CloudFront key pair or a custom trusted signer (such as Lambda Edge) that includes security parameters such as IP restrictions, time windows, and custom policies. The major difference is the content distribution network (CDN) making performance faster by caching data geographically close to the user downloading it.
The built-in logging and monitoring capabilities of CloudFront provide detailed insights into content access patterns, cache hit ratios, and security events. CloudFront integrates seamlessly with Amazon S3 to support origin access identity (OAI), helping to make sure that the S3 objects can be accessed only through CloudFront and not directly through S3 APIs.
Figure 1: CloudFront signed URLs with Amazon S3 architecture
Pros
If Amazon S3 pre-signed URLs sound good, but you need higher performance at a global scale, CloudFront signed URLs are the right choice. The AWS global edge network has points of presence (POPs) all over the world, which significantly reduces latency for users and minimizes data transfer costs through caching. This architecture provides substantial cost savings for frequently accessed content, because edge locations serve cached copies without retrieving objects from the S3 origin. The integration with AWS security services offers protection against various threats, including sophisticated distributed denial of service (DDoS) events and web application issues, making it particularly suitable for public-facing file sharing applications. Choose CloudFront instead of S3 if you tend to make the same file available to many people who download it many times, such as in software distribution or documentation distribution.
The solution’s security model provides extensive flexibility in access control implementation. You can define granular permissions through custom policies, implement geo-restriction rules, and enforce IP-based access controls. The ability to use custom TLS certificates and domains maintains brand consistency while helping to facilitate secure communications. The integration with AWS WAF enables advanced request filtering and rate limiting, while detailed access logging and real-time metrics provide visibility into content delivery and security events. The solution’s support for both signed URLs and signed cookies offers flexibility in implementing various access control scenarios. Signed cookies are used when you want to provide access to multiple restricted files. For example, if you need to provide access to many files in a private directory, you can use signed cookies to avoid having to create individual signed URLs for each file. When choosing between CloudFront signed URLs (ideal for individual file access) or signed cookies (better for providing access to multiple files, like a subscriber’s content library), consider your content distribution needs and whether your clients support cookies.
Cons
If you implement CloudFront, you must develop expertise in its configuration options, including robust key management processes and secure key rotation procedures. Self-managed certificates don’t automatically renew. You must track expiration dates and make sure you renew on time, or your users will get warnings and errors when they try to download. ACM can simplify TLS certificate management and automatically renew certificates before they expire. while trusted signer workflows enhance your security posture.
Note: To create signed URLs, you need a signer. A signer is either a trusted key group that you create in CloudFront, or an AWS account that contains a CloudFront key pair.
Misconfigured web caches have many surprising and frustrating effects for users. Understanding and configuring CloudFront cache behavior is key to helping to prevent unintended content exposure or availability issues. You need to add cache invalidation to your publication workflows so that old versions are no longer available from the cache. This might introduce additional costs and operational overhead, especially in scenarios with frequent content changes. If you frequently change the content that you share, if the content is unique to an individual (such as a personalized report), or if the same content isn’t downloaded many times by many people in many locations, you won’t realize much cost savings or reduced latency from CloudFront caching. The additional complexity added by cache configuration might not be justified unless the cache is used a lot.
If you use the CloudFront global content delivery network, your content will be stored in caches in hundreds of locations around the world. ACM will store your TLS certificates for CloudFront (whether ACM is issuing them or you manage them yourself) in the us-east-1 AWS Region. Because CloudFront is a global service, it automatically distributes the certificate from the us-east-1 Region to the Regions associated with your CloudFront distribution. Caching data and keys around the world might not be acceptable if you have data sovereignty requirements to keep your data in one country.
From a cost perspective, while CloudFront can provide savings through caching, the pricing model has other variables to consider. Data transfer costs vary by Region and can be significant for large-scale distributions. If you need custom domain names and custom TLS certificates, that might introduce additional costs. Implementation expertise is needed when dealing with dynamic content or when specific origin request handling is required. CloudFront only delivers via HTTPS and HTTP protocols, so you won’t be able to use it if you require support for other file transfer protocols. CloudFront distributions provide statistics on cache hit-and-miss rates—pay attention to these because low cache hit rates mean that you’re pulling data from the origin frequently, which limits the possible cost savings.
Amazon VPC endpoint service with custom application
Amazon VPC endpoint services, powered by AWS PrivateLink, enable private connectivity between VPCs without requiring internet access, VPN connections, or direct physical connections. This solution creates a highly secure, private network path for file sharing by exposing services through Network Load Balancers (NLB) and allowing other VPCs to access them through interface endpoints. The architecture isolates the file sharing service from the public internet, operating entirely within the AWS private network infrastructure.
The best use cases for this architecture involve sharing data or distributing software around your AWS infrastructure without exposing it to the public internet.
Figure 2: Amazon VPC endpoint service architecture
The solution, shown in Figure 2, typically involves deploying a custom file sharing application behind an NLB in the service VPC, which is then exposed as an endpoint service. Consumer VPCs create interface endpoints to connect to this service, establishing private connectivity through the AWS backbone network. Traffic remains within the AWS network, is encrypted in transit, and is subject to security controls at both the endpoint and VPC levels. The architecture supports many TCP-based protocols, making it versatile for various file transfer requirements.
This architecture provides secure pathways for data to travel by using multiple layers, including VPC security groups, network access control lists (ACLs), endpoint policies, and the custom application’s authentication mechanisms. The built-in security features of PrivateLink are designed so that only approved AWS principals can create interface endpoints to connect to the service, while detailed VPC flow logs provide network traffic visibility.
Pros
Amazon VPC endpoint services provide complete network isolation and private connectivity that’s inaccessible from the public internet. This reduces the exposure footprint and helps meet security requirements for sensitive data transfer operations. The solution maintains private connectivity across different AWS accounts and Regions while keeping traffic within the AWS network infrastructure.
This solution also provides the most flexible protocol support. Other solutions require you to use HTTPS, AWS API calls (which are HTTPS), or one of the protocols supported by Transfer Family (such as SFTP). If you have software that uses custom protocols, and you need security controls and network isolation, this architecture provides predictable performance through dedicated network paths and supports high throughput requirements without internet bandwidth constraints. The granular control over network security through VPC security groups, network ACLs, and endpoint policies enables organizations to implement defense-in-depth strategies effectively. Additionally, the solution’s integration with AWS Organizations facilitates centralized management and governance across multiple accounts.
Cons
Setting up and maintaining VPC endpoints requires significant expertise in AWS networking, including VPC design, PrivateLink configuration, and network security controls. The initial architecture design must carefully consider IP address management, service quotas, and Regional availability to provide scalability and reliability. Organizations must also develop and maintain the custom file sharing application in addition to the VPC endpoints.
This solution has many components that incur hourly and bandwidth-related charges. Each interface endpoint incurs hourly charges and data processing fees, which can accumulate significantly in multi-VPC or multi-Region deployments. NLBs add another cost component, and you must maintain sufficient capacity for peak loads. The solution also has operational costs because of the need for specialized expertise and ongoing maintenance. Additionally, while the private connectivity model provides superior security, it can make troubleshooting more challenging and might require additional tooling for effective monitoring and diagnostics. The Regional nature of VPC endpoints might necessitate additional architecture for multi-Region deployments, potentially increasing both costs and operational overhead. This solution is most suitable when private network security considerations are the highest priority, and cost considerations are secondary.
Amazon S3 Access Points
Amazon S3 Access Points simplify managing data access at scale for applications using shared data sets on S3. Access points are named network endpoints attached to S3 buckets that streamline managing access to shared datasets. Each access point has its own AWS Identity and Access Management (IAM) policy that controls access to the data, allowing you to create custom access permissions for different applications or user groups accessing the same bucket.
The architecture uses S3 buckets with access points providing dedicated access paths to the data. Each access point has its own hostname (URL) and access policy that works in conjunction with the bucket policy. You can create access points that only allow connections from your Amazon Virtual Private Cloud (Amazon VPC) for private network access to Amazon S3 or create access points with Internet connectivity. You can use this flexibility to implement sophisticated access control patterns while maintaining a single source of truth in S3.
Figure 3: S3 Access Points with VPC endpoints
Pros
Amazon S3 Access Points simplify permissions management and security to accommodate multiple access patterns and use cases. For example, if an S3 bucket contains data that needs to be accessed by multiple applications, each requiring different levels of access, you can create a dedicated access point for each application with precisely the permissions it needs, rather than managing a long monolithic bucket policy.
You can implement access control workflows, such as restricting access to specific VPCs, encryption, or limit access to specific objects or prefixes. The service requires no new infrastructure management, reducing operational overhead and allowing you to focus on business logic implementation.
Access points provide a way to enforce network controls through VPC-only access points, helping to make sure that data can only be accessed from within your private network. IAM permissions management becomes more granular and straightforward to audit when each application or user group has its own access point with a dedicated policy. You can associate different access points with different network origins.
Another possible use case is when you need to provide temporary access to specific data within a bucket without modifying the bucket policy. You can create a temporary access point with the necessary permissions and delete it when the access is no longer needed.
Cons
Access points add another layer to your Amazon S3 architecture that needs to be managed and monitored. Each access point has its own Amazon Resource Name (ARN) and hostname that applications need to use instead of the bucket name, which might require changes to your application code.
There are limits to the number of access points you can create for each bucket, which might be a constraint for large-scale applications. Access points can only control access to the bucket they’re associated with, not across multiple buckets, so if your application needs to access data across buckets, you’ll need multiple access points.
When implementing this solution, you need to design your access point policies to make sure that they work correctly with your bucket policy. Think of your S3 bucket policy as the primary security framework, while access point policies act as specialized gatekeepers. These two layers of security must work in harmony. The bucket policy takes precedence. For example, if your bucket policy explicitly denies access from specific IP ranges, an access point policy can’t override this restriction. This hierarchical relationship requires strategic planning. Start by defining your broad security boundaries in the bucket policy—perhaps allowing access only from specific VPCs or requiring encryption. Then create your access point policies within these boundaries.
While Amazon S3 Access Points offer powerful flexibility, understanding their boundaries is crucial. Cross-account scenarios, common in large enterprises or partner collaborations, require careful configuration. Imagine you’re working with an external auditing firm that needs temporary access to your financial data stored in S3. Setting up a cross-account access point requires creating the access point in your account, configuring a trust policy to allow the external account, verifying that the bucket policy permits access from the access point, and providing the auditors with the access point ARN and necessary IAM permissions in their account. This process maintains tight control over your data while enabling secure cross-account access.
Some Amazon S3 operations are only controlled at the bucket level and can’t be controlled by access points. Core bucket operations such as configuring versioning, logging, managing lifecycle policies, and setting up cross-Region replication require direct bucket access. For these operations, you need to interact directly with the bucket through the appropriate permissions. This limitation helps make sure that fundamental bucket configurations remain centralized and controlled by bucket owners.
Creating a dedicated IAM role for bucket administration tasks—separate from the roles that interact with data through access points—enhances security and aligns with the principle of least privilege.
Conclusion
In this second part of a two-part post, you’ve learned about multiple solutions for secure file sharing using AWS services and the pros and cons of each. You can find additional options and a full decision matrix in Part 1. The optimal solution depends on your specific organizational requirements, technical capabilities, and budget constraints. You don’t have to choose just one option, you can implement multiple solutions to address different use cases, creating a file sharing strategy that balances security, cost, and operational efficiency.
SilverBullet is a MIT-licensed note-taking application, designed to run as a
self-hosted web server. Started in 2022, the project is approaching
its 2.0 release, making this a good time to explore the features it offers.
SilverBullet stores notes as plain
Markdown files, and provides a
Lua
scripting API to customize the application’s appearance and behavior.
Matthew Garrett has posted a detailed followup to
our recent article on the coming
expiration if Microsoft’s Secure Boot signing key.
The upshot is that nobody actually enforces these expiry dates – here’s
the reference code that disables it. In a year’s time we’ll
have gone past the expiration date for ‘Microsoft Windows UEFI
Driver Publisher’ and everything will still be working, and a few
months later ‘Microsoft Windows Production PCA 2011’ will also
expire and systems will keep booting Windows despite being signed
with a now-expired certificate. This isn’t a Y2K scenario where
everything keeps working because people have done a huge amount of
work – it’s a situation where everything keeps working even if
nobody does any work.
The big cloud providers already offer everything you need, including storage. So, why complicate things, right? At first glance, that sounds convincing. Hyperscalers like AWS, Azure, and Google Cloud offer massive service catalogs, global infrastructure, and a wide range of storage options. For many teams, they seem like a convenient one-stop shop.
But in practice, things aren’t nearly as straightforward.
While hyperscalers offer extensive storage capabilities, their multi-tier systems prioritize versatility over optimization. The result? Hidden costs and performance headaches that cloud-native teams can’t afford to ignore.
The claim that hyperscaler storage meets all cloud-native needs because of scale and functionality is a stubborn myth, one of many that still permeate the development landscape.
This post kicks off a blog series tackling these myths and misconceptions about specialized cloud storage and what a best-of-breed, interoperable approach to storage and infrastructure entails.
New Cloud Native Times Call for New Cloud Storage Approaches
Learn more about how the open cloud supports faster development, improved workflows, and reduced cost complexity in our free ebook, “New Cloud Native Times Call for New Cloud Storage Approaches.”
Reading the fine print of hyperscaler storage
On the surface, hyperscaler storage looks comprehensive and capable. But dig a little deeper, and some underlying cracks start to show.
Premium performance isn’t the default
Hyperscalers can deliver high performance, but not without tradeoffs:
They charge more. Premium tiers designed for workloads like analytics or streaming can cost five to eight times more than interoperable solutions.
They prioritize themselves. When hyperscalers face high-performance demands (e.g., AI workloads competing for GPUs and storage bandwidth), they tend to prioritize their own data centers. Smaller teams might have to navigate opaque processes to request higher performance, and their access to advanced optimizations can be limited.
They play favorites. File size adds yet another layer of difficulty. Many hyperscaler storage systems handle large files more efficiently than small ones because of I/O overhead. Hyperscalers may help their biggest customers fine-tune configurations, but most are left to troubleshoot bottlenecks on their own.
Juggling tiers (and hoping nothing gets dropped)
Hot, cool, and cold storage options may look flexible on paper, but they require separate access controls, replication rules, and performance tuning. Teams are left juggling interfaces like AWS Identity and Access Management (IAM), scripting policies, and managing tooling just to keep systems functional.
And the more storage types you manage, the greater the chance for human error. A misplaced lifecycle rule or a mistyped IAM permission can result in:
Unexpected data unavailability
Delayed retrievals
Accidental deletions
When complexity undermines reliability
Keeping storage tied tightly to hyperscaler infrastructure may seem efficient—but it often results in brittle setups. Misaligned storage, compute, and access layers can lead to latency issues or even full-blown downtime.
Performance-sensitive applications like real-time analytics or video streaming suffer most. Even a small delay can ripple through the user experience and cause customer churn. To patch gaps, teams often layer on caches, fine-tuning, or quick fixes that only add technical debt.
Who has time to babysit storage?
Developers, DevOps, and site reliability engineers (SREs) are always racing to ship features, scale services, and maintain uptime. For cloud-native teams, optimizing storage isn’t usually at the top of anyone’s to-do list.
Let’s face it: proactively analyzing storage access patterns and configuring tiering rules takes time that cloud-native teams often don’t have. Many teams therefore operate reactively and address storage issues only after performance degrades or surprise bills arrive.
Support tickets don’t feel your pain
Finally, there’s support. Unless you’re a premium customer paying for top-tier service contracts, you’re often stuck with ticketing systems and community forums. That might suffice for routine issues, but when storage problems impact production workloads, waiting for responses through standard channels adds unnecessary stress and delays.
When one size doesn’t fit your cloud
Unlike hyperscaler storage that takes a one-size-fits-all approach, specialized cloud storage solutions directly tackle these challenges. Backblaze B2 is purpose-built to simplify storage for cloud-native teams:
A single, high-performance tier gives you instant access to all your data, with no tier juggling or lifecycle policies.
Predictable, transparent pricing means no unexpected fees or surprise retrieval charges.
S3-compatible APIs simplify integration, allowing you to plug Backblaze B2 directly into your existing cloud-native stack.
For cloud-native teams who value speed, simplicity, and cost control, specialized storage isn’t a complication; it’s a simplification. You get the performance you need, without the complexity you don’t.
Stay tuned for the next post in this series where we tackle Myth #2: Storage isn’t a big enough problem to remediate. (Spoiler: It is.)
LWN wrote an article which opens with the assertion “Linux users who have Secure Boot enabled on their systems knowingly or unknowingly rely on a key from Microsoft that is set to expire in September”. This is, depending on interpretation, either misleading or just plain wrong, but also there’s not a good source of truth here, so.
First, how does secure boot signing work? Every system that supports UEFI secure boot ships with a set of trusted certificates in a database called “db”. Any binary signed with a chain of certificates that chains to a root in db is trusted, unless either the binary (via hash) or an intermediate certificate is added to “dbx”, a separate database of things whose trust has been revoked[1]. But, in general, the firmware doesn’t care about the intermediate or the number of intermediates or whatever – as long as there’s a valid chain back to a certificate that’s in db, it’s going to be happy.
That’s the conceptual version. What about the real world one? Most x86 systems that implement UEFI secure boot have at least two root certificates in db – one called “Microsoft Windows Production PCA 2011”, and one called “Microsoft Corporation UEFI CA 2011”. The former is the root of a chain used to sign the Windows bootloader, and the latter is the root used to sign, well, everything else.
What is “everything else”? For people in the Linux ecosystem, the most obvious thing is the Shim bootloader that’s used to bridge between the Microsoft root of trust and a given Linux distribution’s root of trust[2]. But that’s not the only third party code executed in the UEFI environment. Graphics cards, network cards, RAID and iSCSI cards and so on all tend to have their own unique initialisation process, and need board-specific drivers. Even if you added support for everything on the market to your system firmware, a system built last year wouldn’t know how to drive a graphics card released this year. Cards need to provide their own drivers, and these drivers are stored in flash on the card so they can be updated. But since UEFI doesn’t have any sandboxing environment, those drivers could do pretty much anything they wanted to. Someone could compromise the UEFI secure boot chain by just plugging in a card with a malicious driver on it, and have that hotpatch the bootloader and introduce a backdoor into your kernel.
This is avoided by enforcing secure boot for these drivers as well. Every plug-in card that carries its own driver has it signed by Microsoft, and up until now that’s been a certificate chain going back to the same “Microsoft Corporation UEFI CA 2011” certificate used in signing Shim. This is important for reasons we’ll get to.
The “Microsoft Windows Production PCA 2011” certificate expires in October 2026, and the “Microsoft Corporation UEFI CA 2011” one in June 2026. These dates are not that far in the future! Most of you have probably at some point tried to visit a website and got an error message telling you that the site’s certificate had expired and that it’s no longer trusted, and so it’s natural to assume that the outcome of time’s arrow marching past those expiry dates would be that systems will stop booting. Thankfully, that’s not what’s going to happen.
First up: if you grab a copy of the Shim currently shipped in Fedora and extract the certificates from it, you’ll learn it’s not directly signed with the “Microsoft Corporation UEFI CA 2011” certificate. Instead, it’s signed with a “Microsoft Windows UEFI Driver Publisher” certificate that chains to the “Microsoft Corporation UEFI CA 2011” certificate. That’s not unusual, intermediates are commonly used and rotated. But if we look more closely at that certificate, we learn that it was issued in 2023 and expired in 2024. Older versions of Shim were signed with older intermediates. A very large number of Linux systems are already booting certificates that have expired, and yet things keep working. Why?
Let’s talk about time. In the ways we care about in this discussion, time is a social construct rather than a meaningful reality. There’s no way for a computer to observe the state of the universe and know what time it is – it needs to be told. It has no idea whether that time is accurate or an elaborate fiction, and so it can’t with any degree of certainty declare that a certificate is valid from an external frame of reference. The failure modes of getting this wrong are also extremely bad! If a system has a GPU that relies on an option ROM, and if you stop trusting the option ROM because either its certificate has genuinely expired or because your clock is wrong, you can’t display any graphical output[3] and the user can’t fix the clock and, well, crap.
The upshot is that nobody actually enforces these expiry dates – here’s the reference code that disables it. In a year’s time we’ll have gone past the expiration date for “Microsoft Windows UEFI Driver Publisher” and everything will still be working, and a few months later “Microsoft Windows Production PCA 2011” will also expire and systems will keep booting Windows despite being signed with a now-expired certificate. This isn’t a Y2K scenario where everything keeps working because people have done a huge amount of work – it’s a situation where everything keeps working even if nobody does any work.
So, uh, what’s the story here? Why is there any engineering effort going on at all? What’s all this talk of new certificates? Why are there sensationalist pieces about how Linux is going to stop working on old computers or new computers or maybe all computers?
Microsoft will shortly start signing things with a new certificate that chains to a new root, and most systems don’t trust that new root. System vendors are supplying updates[4] to their systems to add the new root to the set of trusted keys, and Microsoft has supplied a fallback that can be applied to all systems even without vendor support[5]. If something is signed purely with the new certificate then it won’t boot on something that only trusts the old certificate (which shouldn’t be a realistic scenario due to the above), but if something is signed purely with the old certificate then it won’t boot on something that only trusts the new certificate.
How meaningful a risk is this? We don’t have an explicit statement from Microsoft as yet as to what’s going to happen here, but we expect that there’ll be at least a period of time where Microsoft signs binaries with both the old and the new certificate, and in that case those objects should work just fine on both old and new computers. The problem arises if Microsoft stops signing things with the old certificate, at which point new releases will stop booting on systems that don’t trust the new key (which, again, shouldn’t happen). But even if that does turn out to be a problem, nothing is going to force Linux distributions to stop using existing Shims signed with the old certificate, and having a Shim signed with an old certificate does nothing to stop distributions signing new versions of grub and kernels. In an ideal world we have no reason to ever update Shim[6] and so we just keep on shipping one signed with two certs.
If there’s a point in the future where Microsoft only signs with the new key, and if we were to somehow end up in a world where systems only trust the old key and not the new key[7], then those systems wouldn’t boot with new graphics cards, wouldn’t be able to run new versions of Windows, wouldn’t be able to run any Linux distros that ship with a Shim signed only with the new certificate. That would be bad, but we have a mechanism to avoid it. On the other hand, systems that only trust the new certificate and not the old one would refuse to boot older Linux, wouldn’t support old graphics cards, and also wouldn’t boot old versions of Windows. Nobody wants that, and for the foreseeable future we’re going to see new systems continue trusting the old certificate and old systems have updates that add the new certificate, and everything will just continue working exactly as it does now.
Conclusion: Outside some corner cases, the worst case is you might need to boot an old Linux to update your trusted keys to be able to install a new Linux, and no computer currently running Linux will break in any way whatsoever.
[1] (there’s also a separate revocation mechanism called SBAT which I wrote about here, but it’s not relevant in this scenario)
[2] Microsoft won’t sign GPLed code for reasons I think are unreasonable, so having them sign grub was a non-starter, but also the point of Shim was to allow distributions to have something that doesn’t change often and be able to sign their own bootloaders and kernels and so on without having to have Microsoft involved, which means grub and the kernel can be updated without having to ask Microsoft to sign anything and updates can be pushed without any additional delays
[3] It’s been a long time since graphics cards booted directly into a state that provided any well-defined programming interface. Even back in 90s, cards didn’t present VGA-compatible registers until card-specific code had been executed (hence DEC Alphas having an x86 emulator in their firmware to run the driver on the card). No driver? No video output.
[4] There’s a UEFI-defined mechanism for updating the keys that doesn’t require a full firmware update, and it’ll work on all devices that use the same keys rather than being per-device
[5] Using the generic update without a vendor-specific update means it wouldn’t be possible to issue further updates for the next key rollover, or any additional revocation updates, but I’m hoping to be retired by then and I hope all these computers will also be retired by then
[6] I said this in 2012 and it turned out to be wrong then so it’s probably wrong now sorry, but at least SBAT means we can revoke vulnerable grubs without having to revoke Shim
[7] Which shouldn’t happen! There’s an update to add the new key that should work on all PCs, but there’s always the chance of firmware bugs
Today, we’re announcing the general availability of Amazon DocumentDB Serverless, a new configuration for Amazon DocumentDB (with MongoDB compatibility) that automatically scales compute and memory based on your application’s demand. Amazon DocumentDB Serverless simplifies database management with no upfront commitments or additional costs, offering up to 90 percent cost savings compared to provisioning for peak capacity.
With Amazon DocumentDB Serverless, you can use the same MongoDB compatible-APIs and capabilities as Amazon DocumentDB, including read replicas, Performance Insights, I/O optimized, and integrations with other Amazon Web Services (AWS) services.
Amazon DocumentDB Serverless introduces a new database configuration measured in a DocumentDB Capacity Unit (DCU), a combination of approximately 2 gibibytes (GiB) of memory, corresponding CPU, and networking. It continually tracks utilization of resources such as CPU, memory, and network coming from database operations performed by your application.
Amazon DocumentDB Serverless automatically scales DCUs up or down to meet demand without disrupting database availability. Switching from provisioned instances to serverless in an existing cluster is as straightforward as adding or changing the instance type. This transition doesn’t require any data migration. To learn more, visit How Amazon DocumentDB Serverless works.
Some key use cases and advantages of Amazon DocumentDB Serverless include:
Variable workloads – With Amazon DocumentDB Serverless, you can handle sudden traffic spikes such as periodic promotional events, development and testing environments, and new applications where usage might ramp up quickly. You can also build agentic AI applications that benefit from built-in vector search for Amazon DocumentDB and serverless adaptability to handle dynamically invoked agentic AI workflows.
Multi-tenant workloads – You can use Amazon DocumentDB Serverless to manage individual database capacity across the entire database fleet. You don’t need to manage hundreds or thousands of databases for enterprises applications or multi-tenant environments of a software as a service (SaaS) vendor.
Mixed-use workloads – You can balance read and write capacity in workloads that periodically experience spikes in query traffic, such as online transaction processing (OLTP) applications. By specifying promotion tiers for Amazon DocumentDB Serverless instances in a cluster, you can configure your cluster so that the reader instances can scale independently of the writer instance to handle the additional load.
For steady workloads, Amazon DocumentDB provisioned instances are more suitable. You can select an instance class that offers a predefined amount of memory, CPU power, and I/O bandwidth. If your workload changes when using provisioned instances, you should manually modify the instance class of your writer and readers. Optionally, you can add serverless instances to an existing provisioned Amazon DocumentDB cluster at any time.
Amazon DocumentDB Serverless in action To get started with Amazon DocumentDB Serverless, go to the Amazon DocumentDB console. In the left navigation pane, choose Clusters and Create.
On the Create Amazon DocumentDB cluster page, choose Instance-based cluster type and then Serverless instance configuration. You can choose minimum and maximum capacity DCUs. Amazon DocumentDB Serverless is supported starting with Amazon DocumentDB 5.0.0 and higher with a capacity range of 0.5–256 DCUs.
To add a serverless instance to an existing provisioned cluster, choose Add instances on the Actions menu when you choose the provisioned cluster. If you use a cluster with an earlier version such as 3.6 or 4.0, you should first upgrade the cluster to the supported engine version (5.0).
On the Add instances page, choose Serverless in the DB instance class section for each new serverless instance you want to create. To add another instance, choose Add instance and continue adding instances until you have reached the desired number of new instances. Choose Create.
Now, you can connect to your Amazon DocumentDB cluster using AWS CloudShell. Choose Connect to cluster, and you can see the AWS CloudShell Run command screen. Enter a unique name in New environment name and choose Create and run.
When prompted, enter the password for the Amazon DocumentDB cluster. You’re successfully connected to your Amazon DocumentDB cluster, and you can run a few queries to get familiar with using a document database.
Now available Amazon DocumentDB Serverless is now available starting with Amazon DocumentDB 5.0 for both new and existing clusters. You only pay a flat rate per second of DCU usage. To learn more about pricing details and Regional availability, visit the Amazon DocumentDB pricing page.
As of this writing, just over 4,000 non-merge changesets have been pulled
into the mainline repository during the 6.17 merge window. When he announced
the merge-window opening, Linus Torvalds let it be known that, due to a
busy personal schedule, he was likely to pull changes more quickly than
usual this time around; that has been borne out to some extent. Changes
merged so far are focused on core-kernel and filesystem work; read on for
the details.
Databases and query engines, including Amazon Redshift, often rely on different statistics about the underlying data to determine the most effective way to execute a query, such as the number of distinct values and which values have low selectivity. When Amazon Redshift receives a query, such as
SELECT insert_date, sum(sales)
FROM receipts
WHERE insert_date BETWEEN '2024-12-01' AND '2024-12-31'
GROUP BY insert_date
, the query planner uses statistics to make an educated guess on the most effective method to load and process data from storage. More statistics about the underlying data can often help a query planner select a plan that leads to the best query performance, but this can require a tradeoff among the cost of computing, storing, and maintaining statistics, and might require additional query planning time.
Data lakes are a powerful architecture to organize data for analytical processing, because they let builders use efficient analytical columnar formats like Apache Parquet, while letting them continue to modify the shape of their data as their applications evolve with open table formats like Apache Iceberg. One challenge with data lakes is that they don’t always have statistics about their underlying data, making it difficult for query engines to determine the optimal execution path. This can lead to issues, including slow queries and unexpected changes in query performance.
In 2024, Amazon Redshift customers queried over 77 EB (exabytes) of data residing in data lakes. Given this usage, the Amazon Redshift team works to innovate on data lake query performance to help customers efficiently access their open data to get near real-time insights to make critical business decisions. In 2024, Amazon Redshift launched several features that improve query performance for data lakes, including faster query times when a data lake doesn’t have statistics. With Amazon Redshift patch 190, the TPC-DS 3TB benchmark showed an overall 2x query performance improvement on Apache Iceberg tables without statistics, including TPC-DS Query #72, which improved by 125 times from 690 seconds to 5.5 seconds.
In this post, we first briefly review how planner statistics are collected and what impact they have on queries. Then, we discuss Amazon Redshift features that deliver optimal plans on Iceberg tables and Parquet data even with the lack of statistics. Finally, we review some example queries that now execute faster because of these latest Amazon Redshift innovations.
Prerequisites
The benchmarks in this post were run using the following environment:
Now, let’s review how database statistics work and how they impact query performance.
Overview of the impact of planner statistics on query performance
To understand why database are statistics are important, first let’s review what a query planner does. A query planner is the brain of a database: when you send a query to a database, the query planner must determine the most efficient way to load and compute all of the data required to answer the query. Having information about the underlying dataset, such as statistics about the number of rows in a dataset, or the distribution of data, can help the query planner generate an optimal plan for retrieving the data. Amazon Redshift uses statistics about the underlying data in tables and columns statistics to determine how to build an optimal query execution path.
Let’s see how this works in an example. Consider the following query to determine the top five sales dates in December 2024 for stores in North America:
SELECT insert_date, sum(sales) AS total_sales
FROM receipts
JOIN stores ON stores.id = receipts.store_id
WHERE
  stores.region = 'NAMER' AND
  receipts.insert_date BETWEEN '2024-12-01' AND '2024-12-31'
GROUP BY receipts.insert_date
ORDER BY total_sales DESC
LIMIT 5;
In this query, the query planner has to consider several factors, including:
Which table is larger, stores or receipts? Am I able to query the smaller table first to reduce the amount of searching on the larger table?
Which returns more rows, receipts.insert_date BETWEEN '2024-12-01' AND '2024-12-31' or stores.region = 'NAMER'?
Is there any partitioning on the tables? Can I search over a smaller set of data to speed up the query?
Having information about the underlying data can help to generate an optimal query plan. For example, stores.region = 'NAMER' might only return a few rows (that is, it’s highly selective), meaning it’s more efficient to execute that step of the query first before filtering through the receipts table. What helps a query planner make this decision is the statistics available on columns and tables.
Table statistics (also known as planner statistics) provide a snapshot of the data available in a table to help the query planner make an informed decision on execution strategies. Databases collect table statistics through sampling, which involves reviewing a subset of rows to determine the overall distribution of data. The quality of statistics, including the freshness of data, can significantly impact a query plan, which is why databases will reanalyze and regenerate statistics after a certain threshold of the underlying data changes.
Amazon Redshift supports several table and column level statistics to assist in building query plans. These include:
Statistic
What it is
Impact
Query plan influence
Number of rows (numrows)
Number of rows in a table
Estimates the overall size of query results and JOIN sizes
Decisions on JOIN ordering and algorithms, and resource allocation
Number of distinct values (NDV)
Number of unique values in a column
Estimates selectivity, that is, how many rows will be returned from predicates (for example, WHERE clause) and the size of JOIN results
Decisions on JOIN ordering and algorithms
NULL count
Number of NULL values in a column
Estimates number of rows eliminated by IS NULL or IS NOT NULL
Decisions on filter pushdown (that is, what nodes execute a query) and JOIN strategies
Min/max values
Smallest and largest values in a column
Helps range-based optimizations (for example, WHERE x BETWEEN 10 AND 20)
Decisions on JOIN order and algorithms, and resource allocation
Column size
Total size of column data in memory
Estimates overall size of scans (reading data), JOINs, and query results
Decisions on JOIN algorithms and ordering
Open formats such as Apache Parquet don’t have any of the preceding statistics by default and table formats like Apache Iceberg have a subset of the preceding statistics such as number of rows, NULL count and min/max values. This can make it challenging for query engines to plan efficient queries. Amazon Redshift has added innovations that improve overall query performance on data lake data stored in Apache Iceberg and Apache Parquet formats even when all or partial table or column-level statistics are unavailable. The next section reviews features in Amazon Redshift that help improve query performance on data lakes even when table statistics aren’t present or are limited.
Amazon Redshift features when data lakes don’t have statistics for Iceberg tables and Parquet
As mentioned previously, there are many cases where tables stored in data lakes lack statistics, which creates challenges for query engines to make informed decisions on selecting the best query plan. However, Amazon Redshift has released a series of innovations that improve performance for queries on data lakes even when there aren’t table statistics available. In this section, we review some of these enhancements and how they impact your query performance.
Dynamic partition elimination through distributed joins
Dynamic partition elimination is a query optimization technique that allows Amazon Redshift to skip reading data unnecessarily during query execution on a partitioned table. It does this by determining which partitions of a table are relevant to a query and only scanning those partitions, significantly reducing the amount of data that needs to be processed.
For example, imagine a schema that has two tables:
sales (fact table) with columns:
sale_id
product_id
sale_amount
sale_date
products (dimension table) with columns:
product_id
product_name
category
The sales table is partitioned by product_id. In the following example, you want to find the total sales amount for products in the Electronics category in December 2024.
SQL query:
SELECT SUM(s.sale_amount)
FROM sales s
JOIN products p ON s.product_id = p.product_id
WHERE p.category = 'Electronics';
How Amazon Redshift improves this query:
Filter on dimension table:
The query filters the products table to only include products in the Electronics category.
Identify relevant partitions:
With the new improvements, Amazon Redshift analyzes this filter and determines which partitions of the sales table need to be scanned.
It looks at the product_id values in the products table that match the Electronics category and only scans those specific partitions in the sales table.
Instead of scanning the entire sales table, Amazon Redshift only scans the partitions that contain sales data for electronics products.
This significantly reduces the amount of data Amazon Redshift needs to process, making the query faster.
Previously, this optimization was only applied on broadcast joins when all child joins below the join were also broadcast joins. The Amazon Redshift team extended this capability to work on all broadcast joins, regardless if the child joins below them are broadcast. This allows more queries to benefit from dynamic partition elimination, such as TPC-DS Q64 and Q75 for Iceberg tables, and TPC-DS Q25 in Parquet.
Metadata caching for Iceberg tables
The Iceberg open table format employs a two-layer structure: a metadata layer and a data layer. The metadata layer has three levels of files (metadata.json, manifest lists, and manifests), which allows for performance features such as faster scan planning and advanced data filtering. Amazon Redshift uses the Iceberg metadata structure to efficiently identify the relevant data files to scan, using partition value ranges and column-level statistics and eliminating unnecessary data processing.
The Amazon Redshift team observed that Iceberg metadata is frequently fetched multiple times both within and across queries, leading to potential performance bottlenecks. We implemented an in-memory LRU (least recently used) cache for parsed metadata, manifest list files, and manifest files. This cache keeps the most recently used metadata so that we avoid fetching them repeatedly from Amazon Simple Storage Service (Amazon S3) across queries. This caching has helped with overall performance improvements of up to 2% in a TPC-DS 3TB workload. We observe more than 90% cache hits for these metadata structures, reducing the iceberg metadata processing times considerably.
Stats inference for Iceberg tables
As mentioned previously, the Apache Iceberg file format comes with some statistics such as number of rows, number of nulls, column min/max values and column storage size in the metadata files called manifest files. However, they don’t always provide all the statistics that we need especially average width which is important for the cost-based optimizer used by Amazon Redshift.
We delivered a feature to estimate average width for variable length columns such as string and binary from Iceberg metadata. We do this by using the column storage size and the number of rows, and we adjust for column compression when necessary. By inferring these additional statistics, our optimizer can make more accurate cost estimates for different query plans. This stats inference feature, released in Amazon Redshift patch 186, offers up to a 7% improvement in the TPC-DS benchmarks. We have also enhanced Amazon Redshift optimizer’s cost model. The enhancements include planner optimizations that improve the estimations of the different join distribution strategies to take into account the networking cost of distributing the data between the nodes of an Amazon Redshift cluster. The enhancements also include improvements to Amazon Redshift query optimizer. These enhancements, which are a culmination of several years of research, testing, and implementation demonstrated up to a 45% improvement in a collection of TPC-DS benchmarks.
Example: TPC-DS benchmark highlights on Amazon Redshift no stats queries on data lakes
One way to measure data lake query performance for Amazon Redshift is using the TPC-DS benchmark. The TPC-DS benchmark is a standardized benchmark designed to test decision support systems, specifically looking at concurrently accessed systems where queries can range from shorter analytical queries (for example, reporting, dashboards) to longer running ETL-style queries for moving and transforming data into a different system. For these tests, we used the Cloud Data Warehouse Benchmark derived from the TPC-DS 3TB to align our testing with many common analytical workloads, and provide a standard set of comparisons to measure improvements to Amazon Redshift data lake query performance.
We ran these tests across data stored both in the Apache Parquet data format, in addition to Apache Iceberg tables with data in Apache Parquet files. Because we focused these tests on out-of-the-box performance, none of these data sets had any table statistics available. We performed these tests using the specified Amazon Redshift patch versions in the following table, and used Amazon Redshift Serverless with 88 RPU without any additional tuning. The following results represent a power run, which is the sum of how long it took to run all the tests, from a warm run, which are the results of the power run after at least one execution of the workload:
P180 (12/2023)
P190 (5/2025)
Apache Parquet (only numrows)
7,796
3,553
Apache Iceberg (out-of-the-box, no tuning)
4,411
1,937
We saw notable improvements in several query run times. For this post, we focus on the improvements we saw in query 82:
SELECT
    i_brand_id brand_id, i_brand brand,
    sum(ss_ext_sales_price) ext_price
FROM date_dim, store_sales, item
WHERE d_date_sk = ss_sold_date_sk AND
    ss_item_sk = i_item_sk AND
    i_manager_id = 83 AND
    d_moy = 12 AND
    d_year = 2002
GROUP BY i_brand, i_brand_id
ORDER BY ext_price desc, i_brand_id
LIMIT 100;
In this query, we’re searching for the top 100 selling brands from a specific manager in December 2002, which represents a typically dashboard-style analytical query. In our power run, we saw a reduction in query time from 512 seconds to 18.1 seconds for Apache Parquet data, or a 28.2x improvement in performance. The accelerated query performance for this query in a warm run is due to the improvements to the cost-based optimizer and dynamic partition elimination.
If you ran these tests on your own and don’t need the resources anymore, you’ll need to delete your Amazon Redshift Serverless workgroup. See Shutting down and deleting a cluster. If you don’t need to store the Cloud Data Warehouse Benchmark data in your S3 bucket anymore, see Deleting Amazon S3 objects.
Conclusion
In this post, you learned how cost-based optimizers for databases work, and how statistical information about your data can help Amazon Redshift execute queries more efficiently. You can optimize query performance for Iceberg tables by automatically collecting Puffin statistics, which lets Amazon Redshift use these recent innovations to more efficiently query your data. Giving more info to your query planner—the brain of Amazon Redshift—helps to provide more predictable performance and helps you to further scale how you interact with your data in your data lakes and data lakehouses.
About the authors
Martin Milenkoski is a Software Development Engineer on the Amazon Redshift team, currently focusing on data lake performance and query optimization. Martin holds an MSc in Computer Science from the École Polytechnique Fédérale de Lausanne.
Kalaiselvi Kamaraj is a Sr. Software Development Engineer on the Amazon Redshift team. She has worked on several projects within the Amazon Redshift Query processing team and currently focusing on performance related projects for Amazon Redshift DataLake and query optimizer.
Jonathan Katz is a Principal Product Manager – Technical on the AWS Analytics team and is based in New York. He is a Core Team member of the open-source PostgreSQL project and an active open-source contributor, including to the pgvector project.
Business and technology leaders are constantly striving to improve productivity, increase velocity, foster experimentation, reduce time-to-market (TTM), and enhance the developer experience. These North Star goals drive innovation in software development practices. This innovation is increasingly being powered by artificial intelligence. Particularly, generative AI powered tools such as Amazon Q Developer and Kiro have already begun to revolutionize how software is created. As things stand, organizations employ AI in software development through two primary approaches: AI-assisted development, where AI enhances specific tasks like documentation, code completion, and testing; and AI-autonomous development, where AI generates entire applications with human oversight.
Why do we need a transformative approach to AI in software?
Our existing software development methods, are designed for human-driven, long running processes, with product owners, developers, architects alike spending most of their time on non-core activities such as planning, meetings, and other software development lifecycle (SDLC) rituals. Simply retrofitting AI as an assistant not only constrains its capabilities but also reinforces outdated inefficiencies. To truly harness AI’s power and achieve the productivity North Star goals, we need to reimagine our entire approach to the software development lifecycle.
To achieve transformative results, we need to position AI as a central collaborator and teammate in the development process, and leverage its capabilities throughout the software development lifecycle. This is why we’re introducing the AI-Driven Development Lifecycle (AI-DLC), a new methodology designed to fully ingrain AI capabilities into the very fabric of software development.
What is AI Driven Development Life Cycle (AI-DLC)?
AI-DLC is an AI-centric transformative approach to software development that emphasizes two powerful dimensions:
AI Powered Execution with Human Oversight: AI systematically creates detailed work plans, actively seeks clarification and guidance, and defers critical decisions to humans. This is critical since only humans possess the contextual understanding and knowledge of business requirements needed to make informed choices.
Dynamic Team Collaboration: As AI handles the routine tasks, teams unite in collaborative spaces for real-time problem solving, creative thinking and rapid-decision-making. This shift from isolated work to high-energy teamwork accelerates innovation and delivery.
These two dimensions enable you to deliver software faster without compromising on quality.
How does AI-DLC work?
At its core, AI-DLC operates by having AI initiate and direct workflows through a new mental model:
This pattern, where AI creates a plan, asks clarifying questions to seek context, and implements solutions only after receiving human validation, repeats rapidly for every SDLC activity, to provide a unified vision and approach for all development pathways.
With this mental model at its core, the software development in AI-DLC takes place in three straightforward phases:
In the Inception phase, AI transforms business intent into detailed requirements, stories and units through “Mob Elaboration” – where the entire team actively validates AI’s questions and proposals.
In the Construction phase, using the validated context from the Inception phase, AI proposes a logical architecture, domain models, code solution and tests through “Mob Construction” – where the team provides clarification on technical decisions and architectural choices in real time.
In the Operations phase, AI applies the accumulated context from previous phases to manage infrastructure as code and deployments, with team oversight.
Each phase provides richer context for the next, thus enabling AI to provide increasingly informed suggestions.
AI saves and maintains persistent context across all phases by storing plans, requirements, and design artifacts to your project repository, ensuring seamless continuation of work across multiple sessions.
AI-DLC introduces new terminology and rituals to reflect its AI-driven, highly collaborative approach. Traditional ‘sprints’ are replaced by ‘bolts’ – shorter, more intense work cycles measured in hours or days rather than weeks; Epics are replaced by Units of Work. This shift in terminology underscores the method’s emphasis on speed and continuous delivery. Similarly, other familiar Agile terms are reimagined to align with the AI-centric workflow, creating a vocabulary that better represents the methodology’s innovative approach to software development.
What are the benefits of this methodology?
Velocity: The foremost benefit that AI-DLC offers is acceleration in development velocity, as AI rapidly generates and refines artifacts, such as requirements, stories, designs, code, and tests allowing product owners, architects, and developers to complete tasks in hours or days that previously took weeks.
Innovation: Consequently, this acceleration and heavy lifting by AI, frees up significant time for innovation, enabling builders to explore creative solutions and push the boundaries of what’s possible.
Quality: With continuous clarification, teams build precisely what they have in mind, rather than an abstract AI interpretation of the intent. This results in products that are more closely aligned with business objectives. AI enhances quality by consistently applying organization-specific standards – your coding practices, design patterns, and security requirements – while generating comprehensive test suites. This end-to-end AI integration improves coherence and traceability from requirements to deployment.
Market Responsiveness: The rapid development cycles of AI-DLC enable us to quickly respond to market demands and user feedback, and consequently faster adaptation to requirements.
Developer Experience: AI-DLC transforms the developer experience by shifting focus from routine coding tasks to critical problem-solving. AI helps reduce cognitive load by handling repetitive tasks, while satisfaction is enhanced as developers gain deeper business context and witness how their work directly impacts business value.
How do I get started with this?
Begin your journey with AI-DLC, through three clear paths: Read the comprehensive AI-DLC white paper, explore how Amazon Q Developer rules and Kiro custom workflows can help you implement AI-DLC in your organization consistently or connect with your AWS account team to discuss how AI-DLC can be tailored to your organization’s specific needs.
The future of software development is here. We are excited to help you leverage AI to not only build systems faster but also maintain fidelity and quality through critical human oversight and collaboration. Start your AI-DLC journey today and join the growing community of organizations transforming their development practices through AI-driven innovation.
Peter Gutmann and Stephan Neuhaus have a new paper—I think it’s new, even though it has a March 2025 date—that makes the argument that we shouldn’t trust any of the quantum factorization benchmarks, because everyone has been cooking the books:
Similarly, quantum factorisation is performed using sleight-of-hand numbers that have been selected to make them very easy to factorise using a physics experiment and, by extension, a VIC-20, an abacus, and a dog. A standard technique is to ensure that the factors differ by only a few bits that can then be found using a simple search-based approach that has nothing to do with factorisation…. Note that such a value would never be encountered in the real world since the RSA key generation process typically requires that |p-q| > 100 or more bits [9]. As one analysis puts it, “Instead of waiting for the hardware to improve by yet further orders of magnitude, researchers began inventing better and better tricks for factoring numbers by exploiting their hidden structure” [10].
A second technique used in quantum factorisation is to use preprocessing on a computer to transform the value being factorised into an entirely different form or even a different problem to solve which is then amenable to being solved via a physics experiment…
Lots more in the paper, which is titled “Replication of Quantum Factorisation Records with an 8-bit Home Computer, an Abacus, and a Dog.” He points out the largest number that has been factored legitimately by a quantum computer is 35.
I hadn’t known these details, but I’m not surprised. I havelongsaid that the engineering problems between now and a useful, working quantum computer are hard. And by “hard,” we don’t know if it’s “land a person on the surface of the moon” hard, or “land a person on the surface of the sun” hard. They’re both hard, but very different. And we’re going to hit those engineering problems one by one, as we continue to develop the technology. While I don’t think quantum computing is “surface of the sun” hard, I don’t expect them to be factoring RSA moduli anytime soon. And—even there—I expect lots of engineering challenges in making Shor’s Algorithm work on an actual quantum computer with large numbers.
Today’s blog is the second in a mini-series of three sharing our experiences of adapting computing curriculum resources for different contexts, and off training teachers to use them in schools. Last month we wrote about our collaboration with partners in Kenya. Here we discuss our work in Odisha, India.
This article has been written by Fiona Coventry, Impact Manager, and Mamta Manaktala, Senior Learning Manager.
A long-term partnership in Odisha
We know that building long-term partnerships with organisations that have local expertise is key to making a real impact for young people. This fact was echoed by people involved in education initiatives worldwide who spoke at the What Works Hub for Global Education 2024 annual conference, which Fiona followed online. Our work in Odisha is an example of this.
Adaptation is a crucial aspect of how we ensure our computing resources are accessible to as many young people as possible. For our work in Odisha, we adapted content from The Computing Curriculum and then localised it to fit the requirement of the students.
In Odisha’s June 2024 to April 2025 academic year, we rolled out adapted computing curriculum content for grade 10 students, for students who had already learned with adapted grade 9 content in 2023/24. We worked with our partners to develop the curriculum content and trained 310 master teachers from across Odisha, along with 30 State Resource Groups (SRGs) to support them. Before the end of 2024, the 310 master teachers subsequently trained 8109 teachers, who would reach an estimated 880,000 students with the grade 9 and 10 curriculum content. We had an ongoing responsibility to support 1846 of these teachers in our allocated districts, with an estimated reach to around 205,000 students.
Impact of the grade 9 and 10 curriculum
In early 2025 we issued a follow-up survey about student learning, content, and training to a sample of teachers in our allocated districts, and 310 teachers responded. (We used a stratified sampling approach designed to ensure the survey results were representative of all teachers.)
At least 87% of teachers agreed that students achieved the outcomes we asked about, e.g. regarding coding skills, staying safe online, and use of data in machine intelligence.
Moreover, responses related to our grade 9 curriculum remained similarly high compared to 2024 survey responses.
2025 Odisha teacher survey responses regarding their students’ learning. Click to enlarge.
Teachers also expressed their appreciation for the computing curriculum resources and training in free-text comments and interviews, for example:
“IT and coding is essential nowadays. So a good initiative, adding this to schools’ curriculum.” – Teacher in Odisha
“The training was quite informative, interesting and helpful.” – Teacher in Odisha
“It is very useful training for me. It boosts my knowledge and helps me for classroom transaction.” – Teacher in Odisha
Addressing challenges
An ongoing challenge in Odisha has been supporting those teachers who lack experience with computing and/or with our recommended teaching approaches for computing. We have been working hard to help these teachers develop the knowledge, skills, and confidence to effectively deliver the curriculum content in the limited time they have alongside their other professional commitments.
In the 2023/2024 academic year, many teachers had told us they needed further training and support. For this reason, we offered longer training in the 2024/25 academic year. We also adapted our training approach based on learning from earlier phases, such as including activities teachers could complete on their smartphones, enabling more hands-on learning while reducing dependence on available IT equipment. The outcome of this was positive: in the follow-up survey, fewer teachers felt they needed additional training to deliver the lessons, and most teachers we interviewed felt this year’s training was an improvement on the previous year’s.
Our team also ran weekly webinars to support teachers and address their queries. These were very well received by teachers. Of the responses received to feedback form available after each webinar:
97% agreed that the “webinar helped me to understand the topics covered more clearly.”
98% agreed that the “webinar was useful to support my teaching.”
This was supported by comments from teachers, for example:
“All questions were answered. The webinar was good. Gained a lot. Thank you very much.” – Teacher in Odisha
“I learned many unknown things about Scratch, it will help my classroom teaching.” – Teacher in Odisha
In this year’s follow-up survey, teachers also less frequently indicated they felt they needed “additional content to support students”. They provided useful feedback and suggestions regarding the curriculum content, e.g. further simplifying and localising it, which we will incorporate into future resource development.
Another persistent challenge has been limited access to IT equipment and the internet in schools, and what this means for student-device ratios and how teachers are able to deliver the content. For future resources we are developing, we are therefore adapting the amount of content to be delivered over a series of lessons.
Next steps for our partnership in Odisha
In 2025, we are working with the same partners to implement a curriculum for grades 6 to 8, initially in around 460 schools. We and our partners have developed the curriculum content and are currently in the process of training teachers in preparation for classroom delivery.
We are also continuing to support the teachers previously trained on the grade 9 and 10 curriculum through webinars and school visits.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
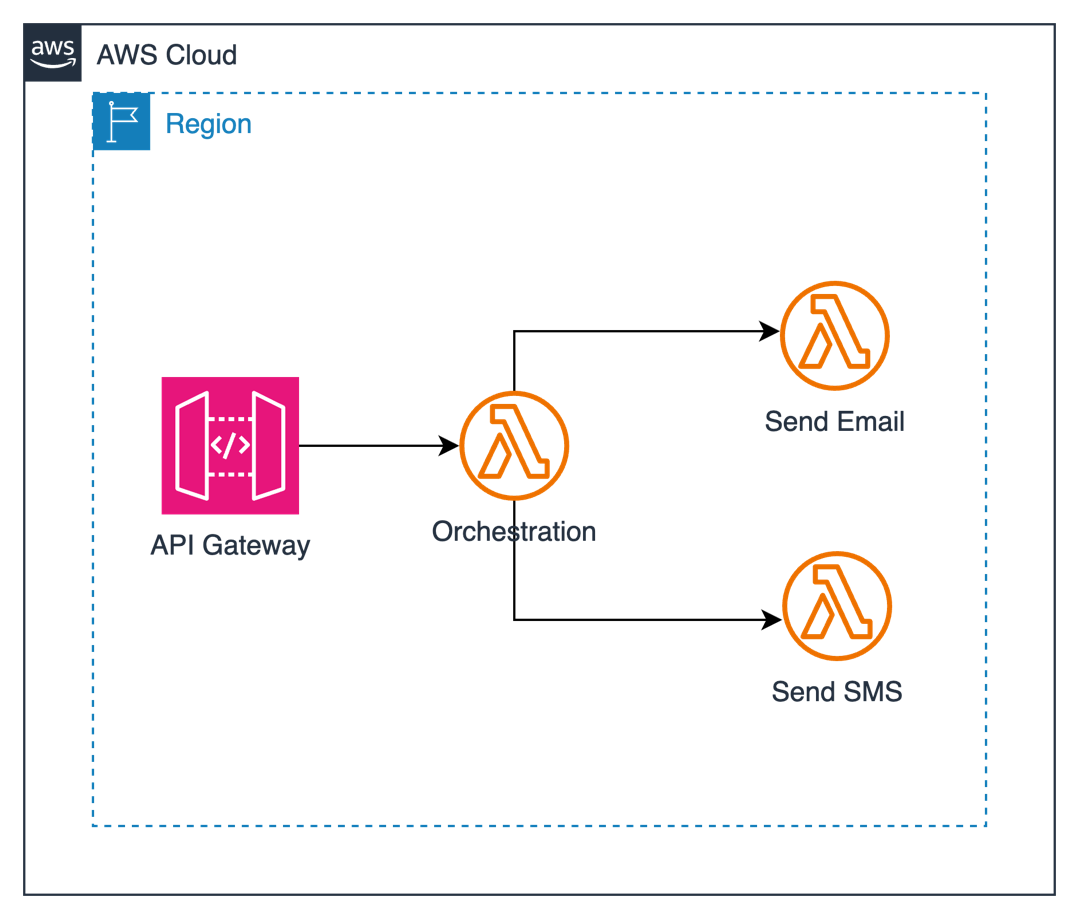
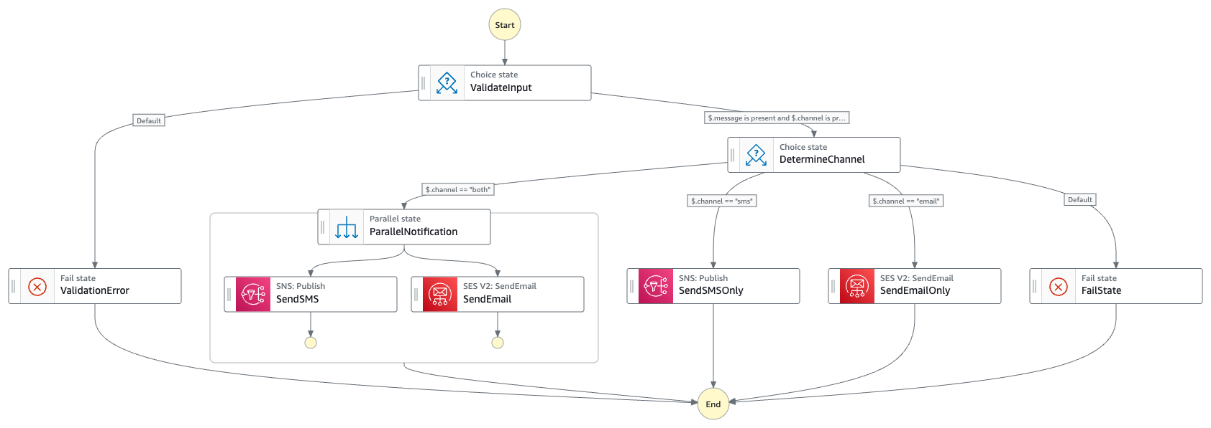
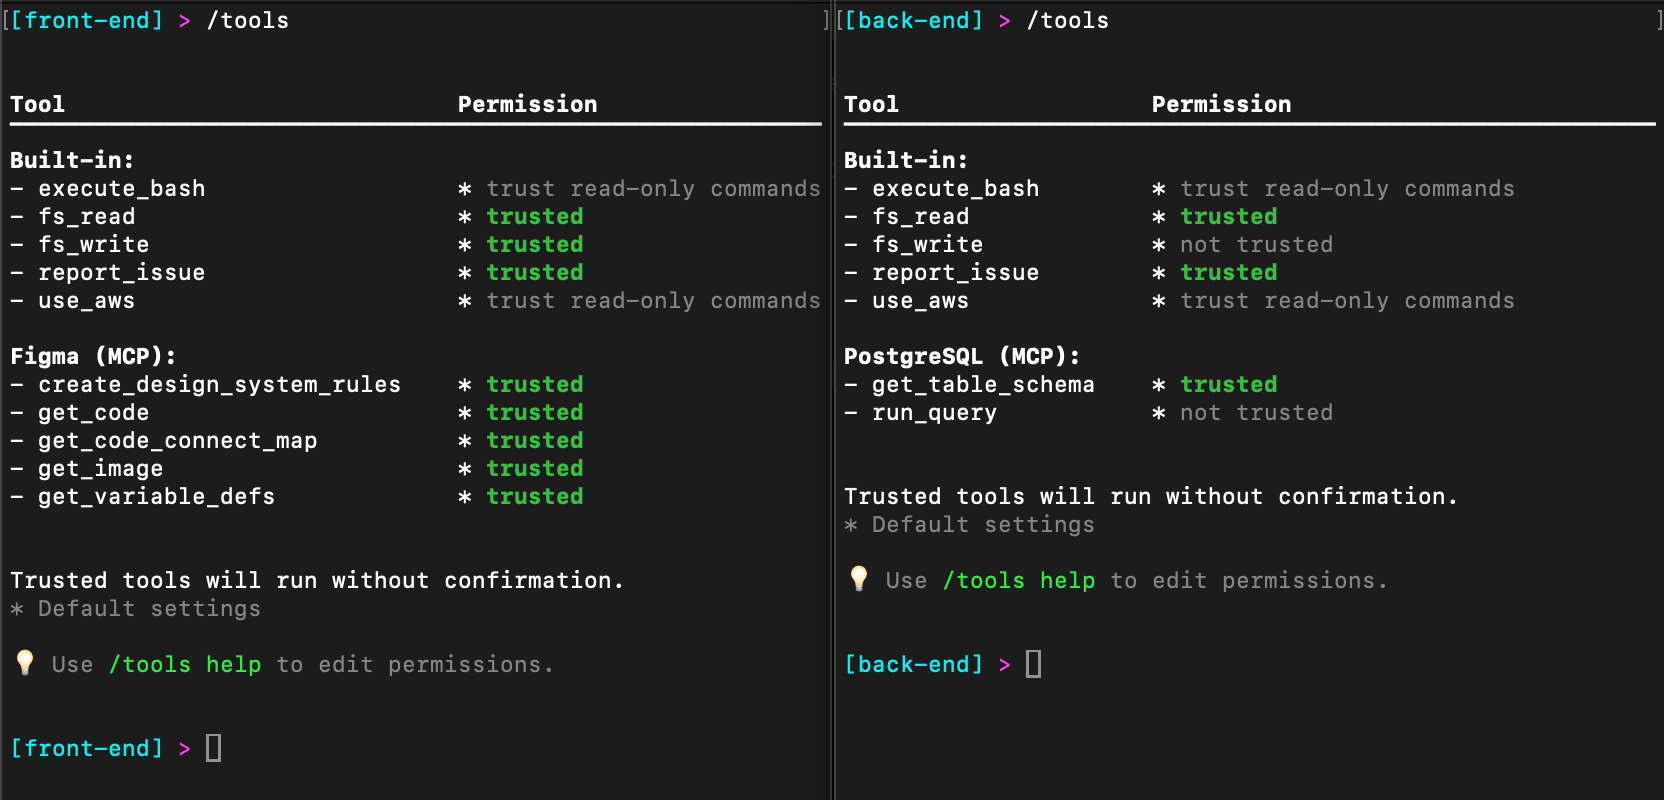
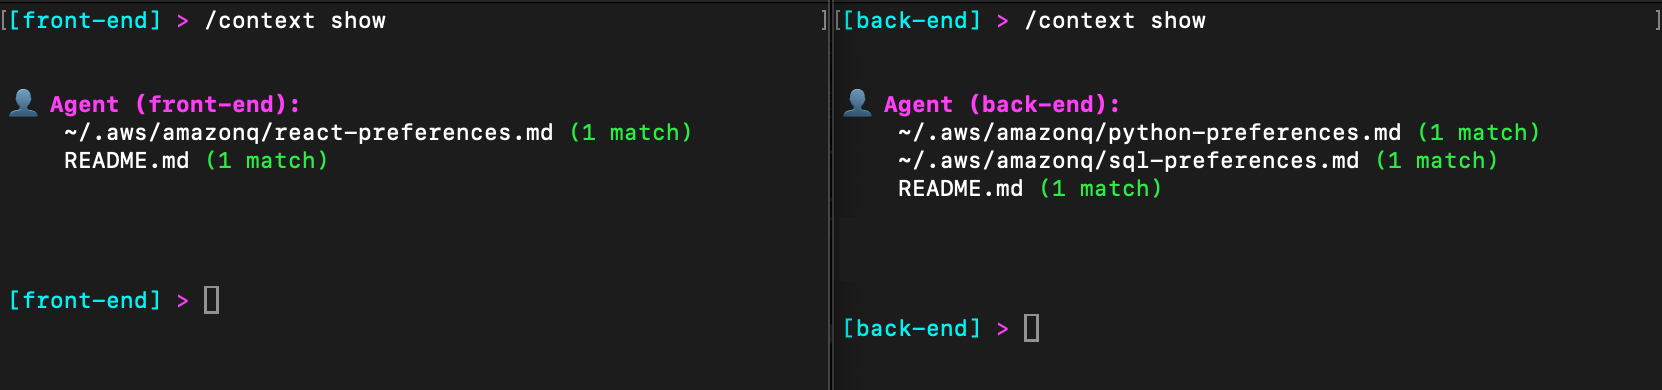
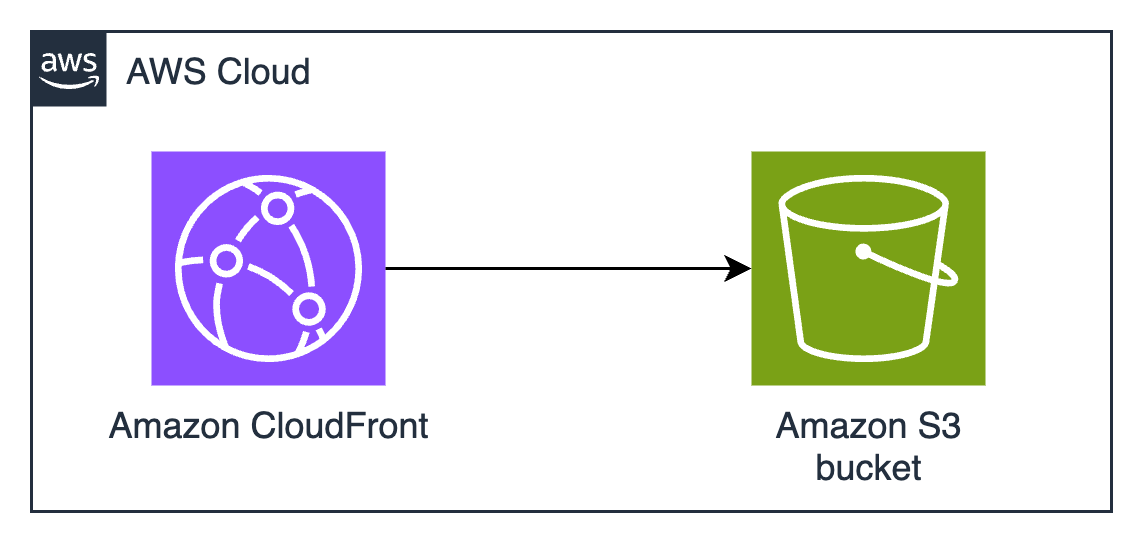
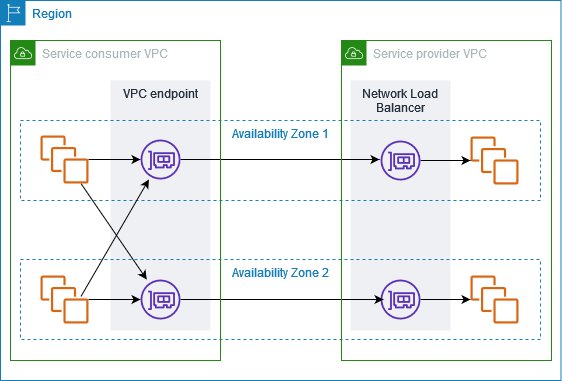
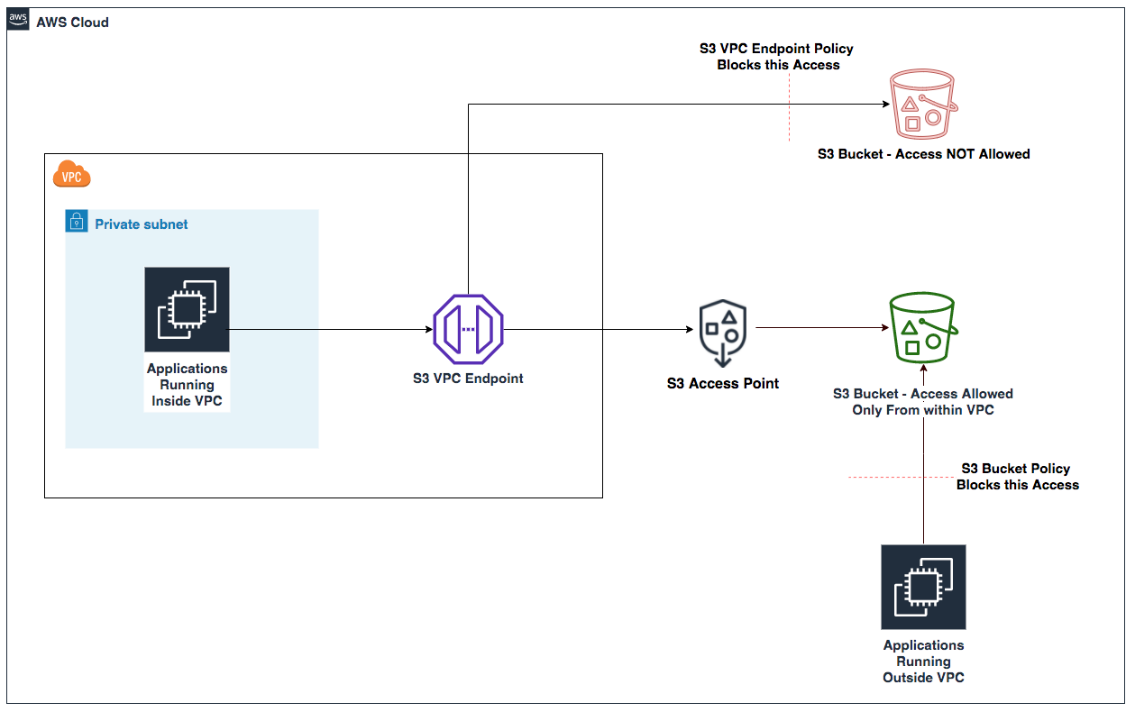

 comments
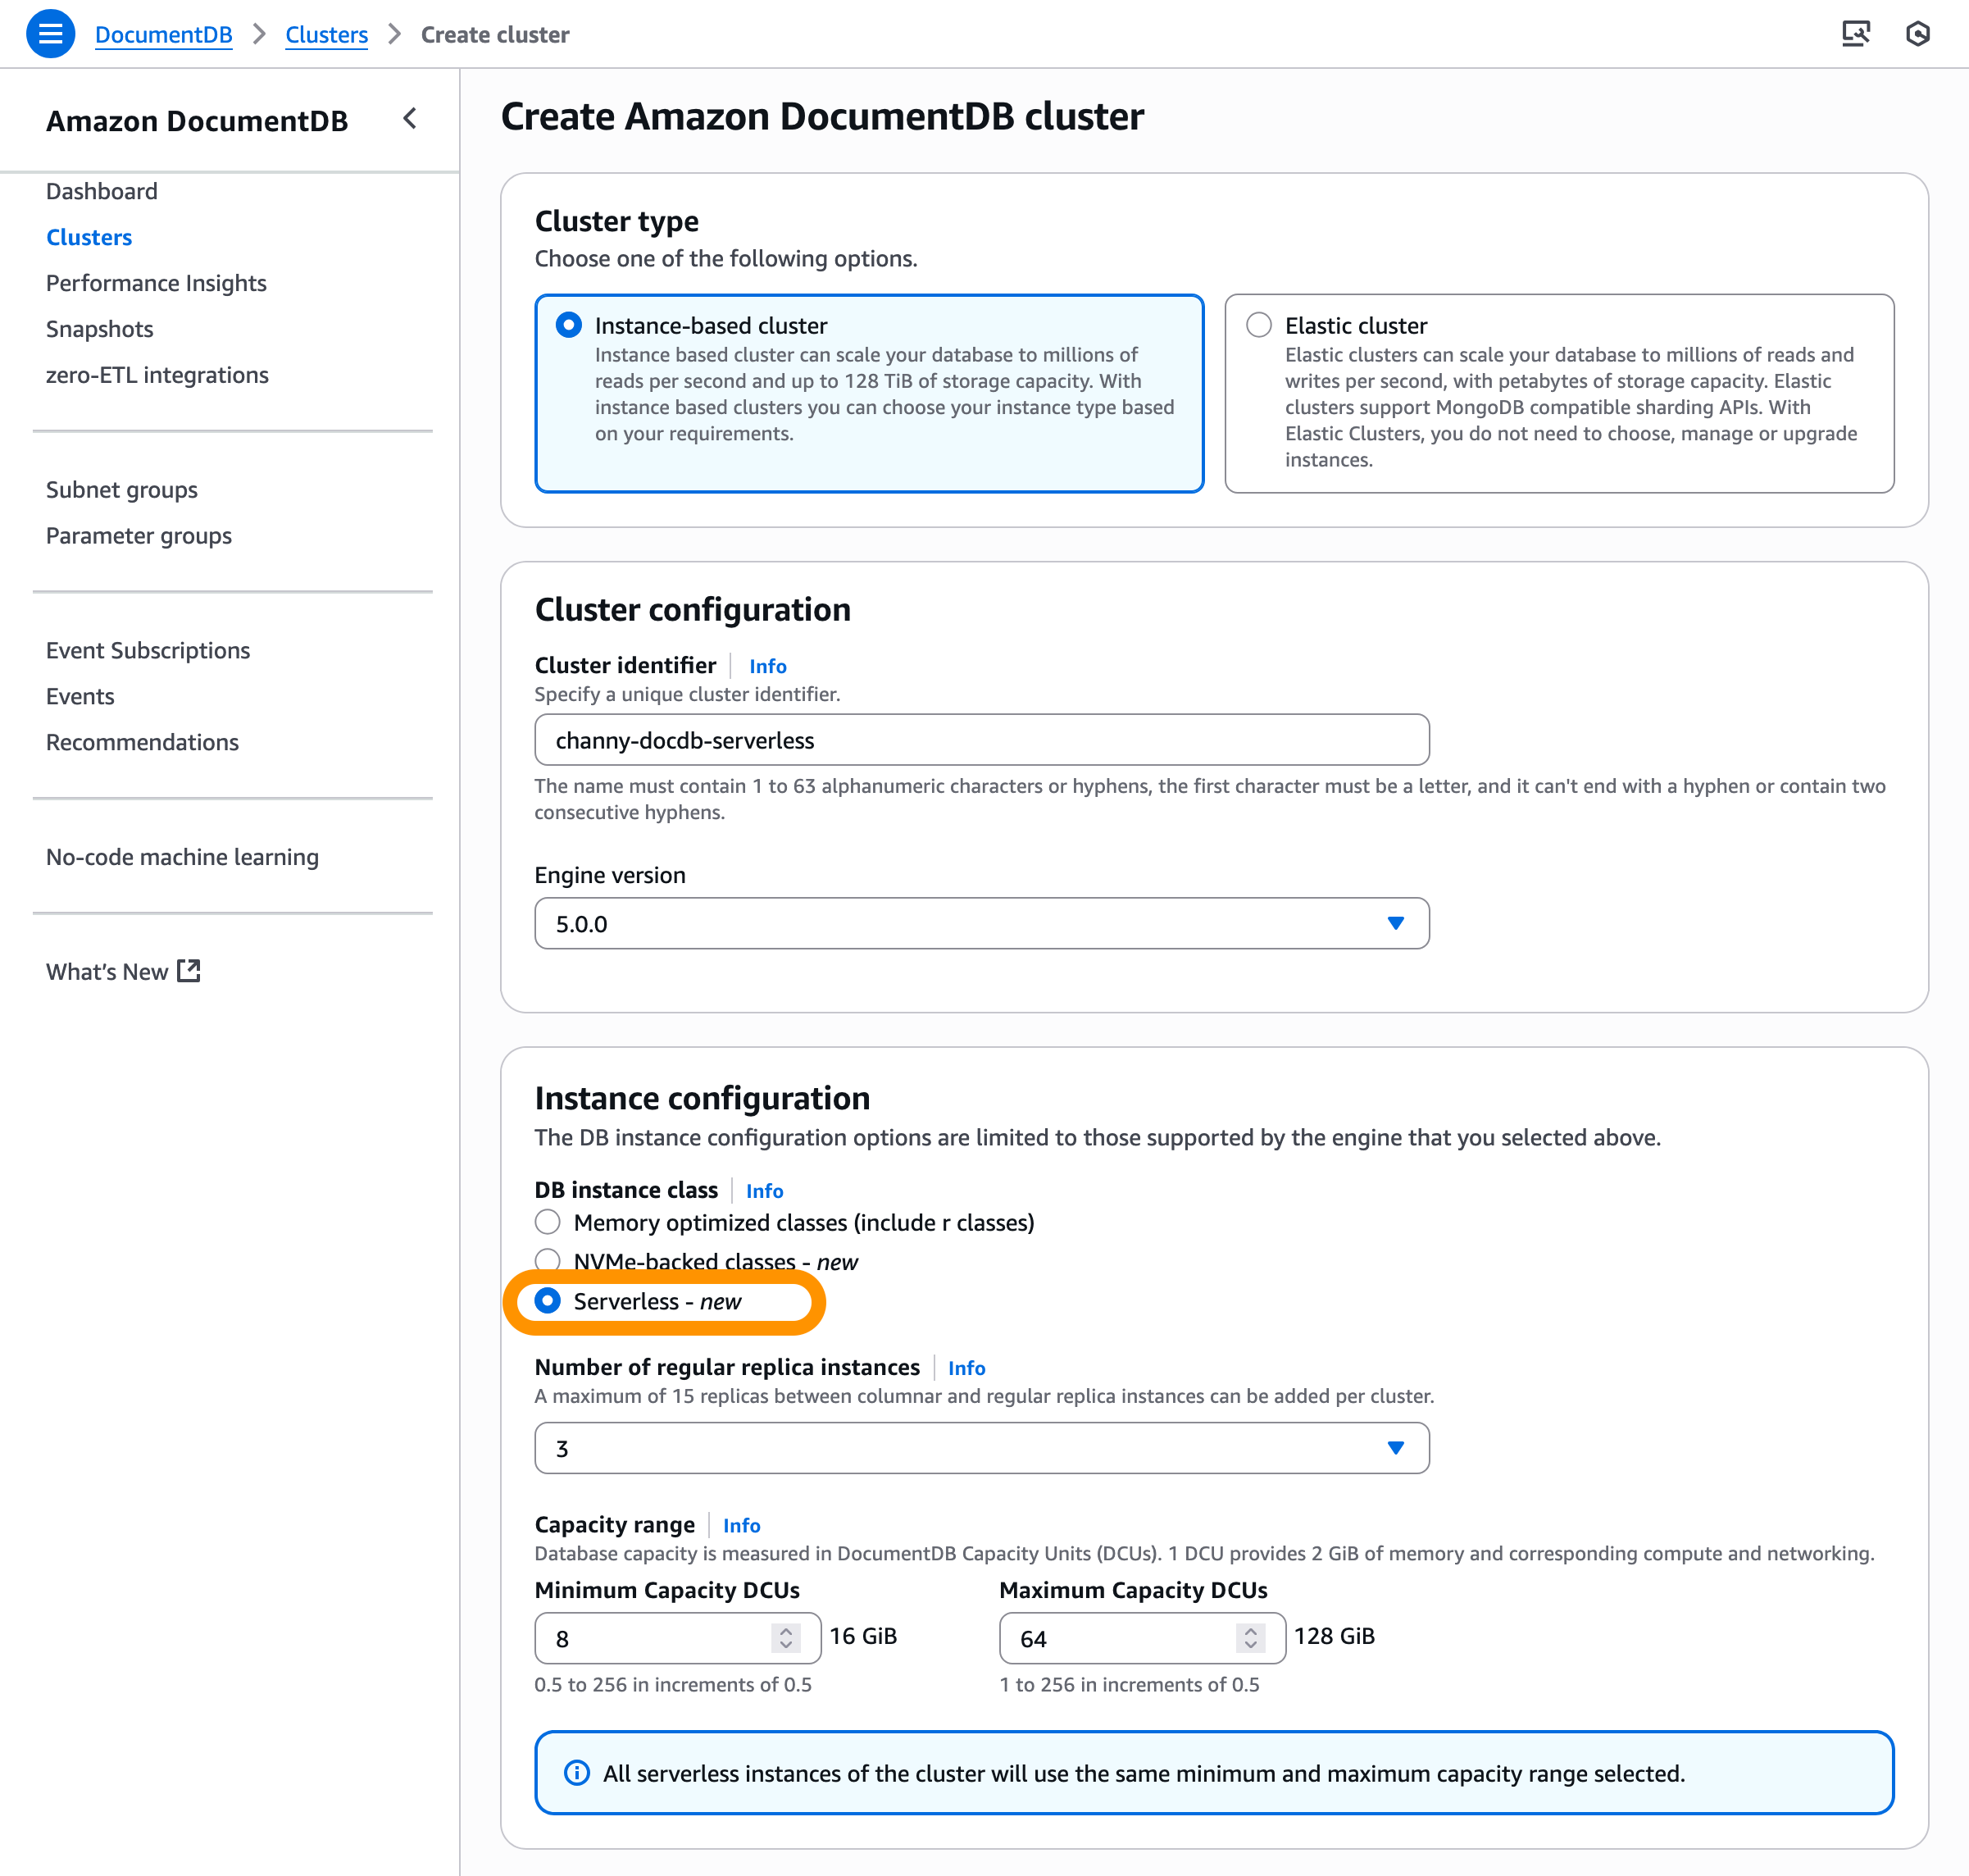
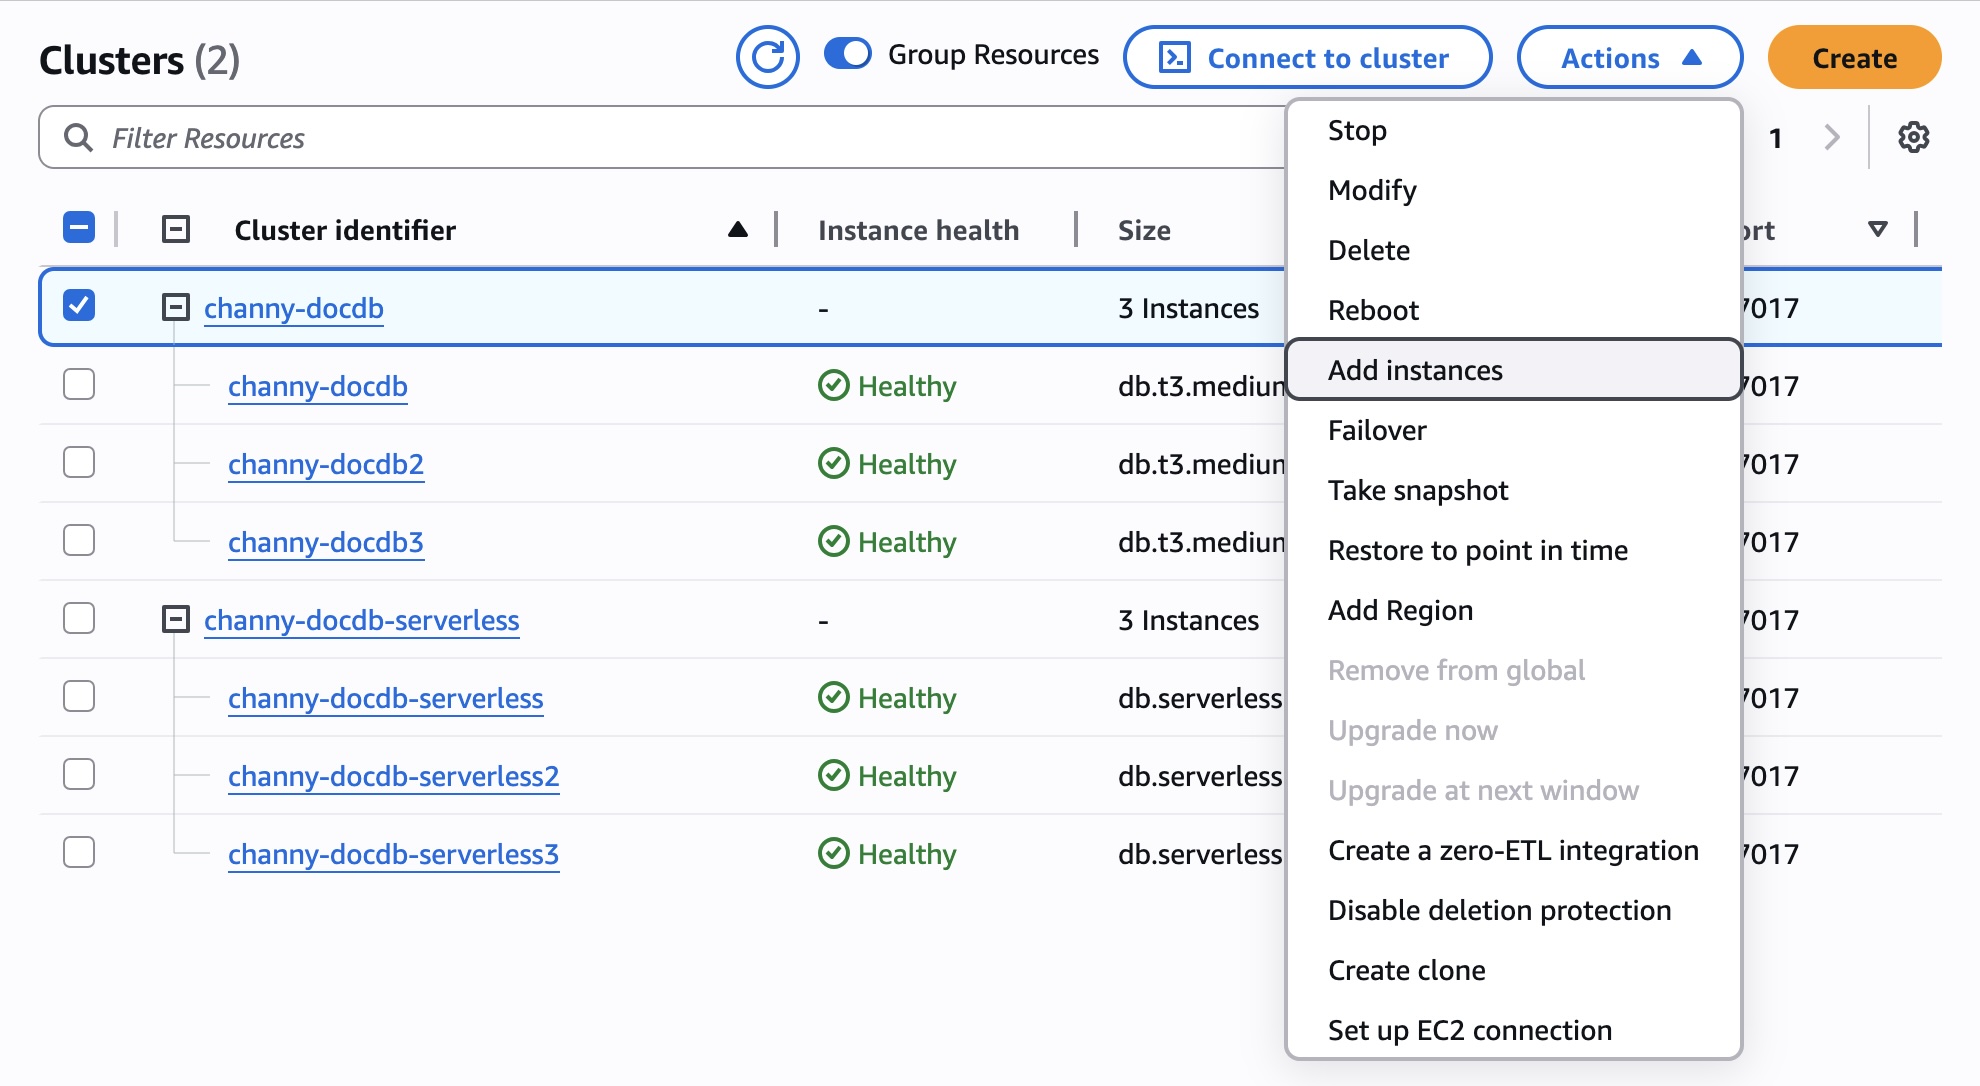
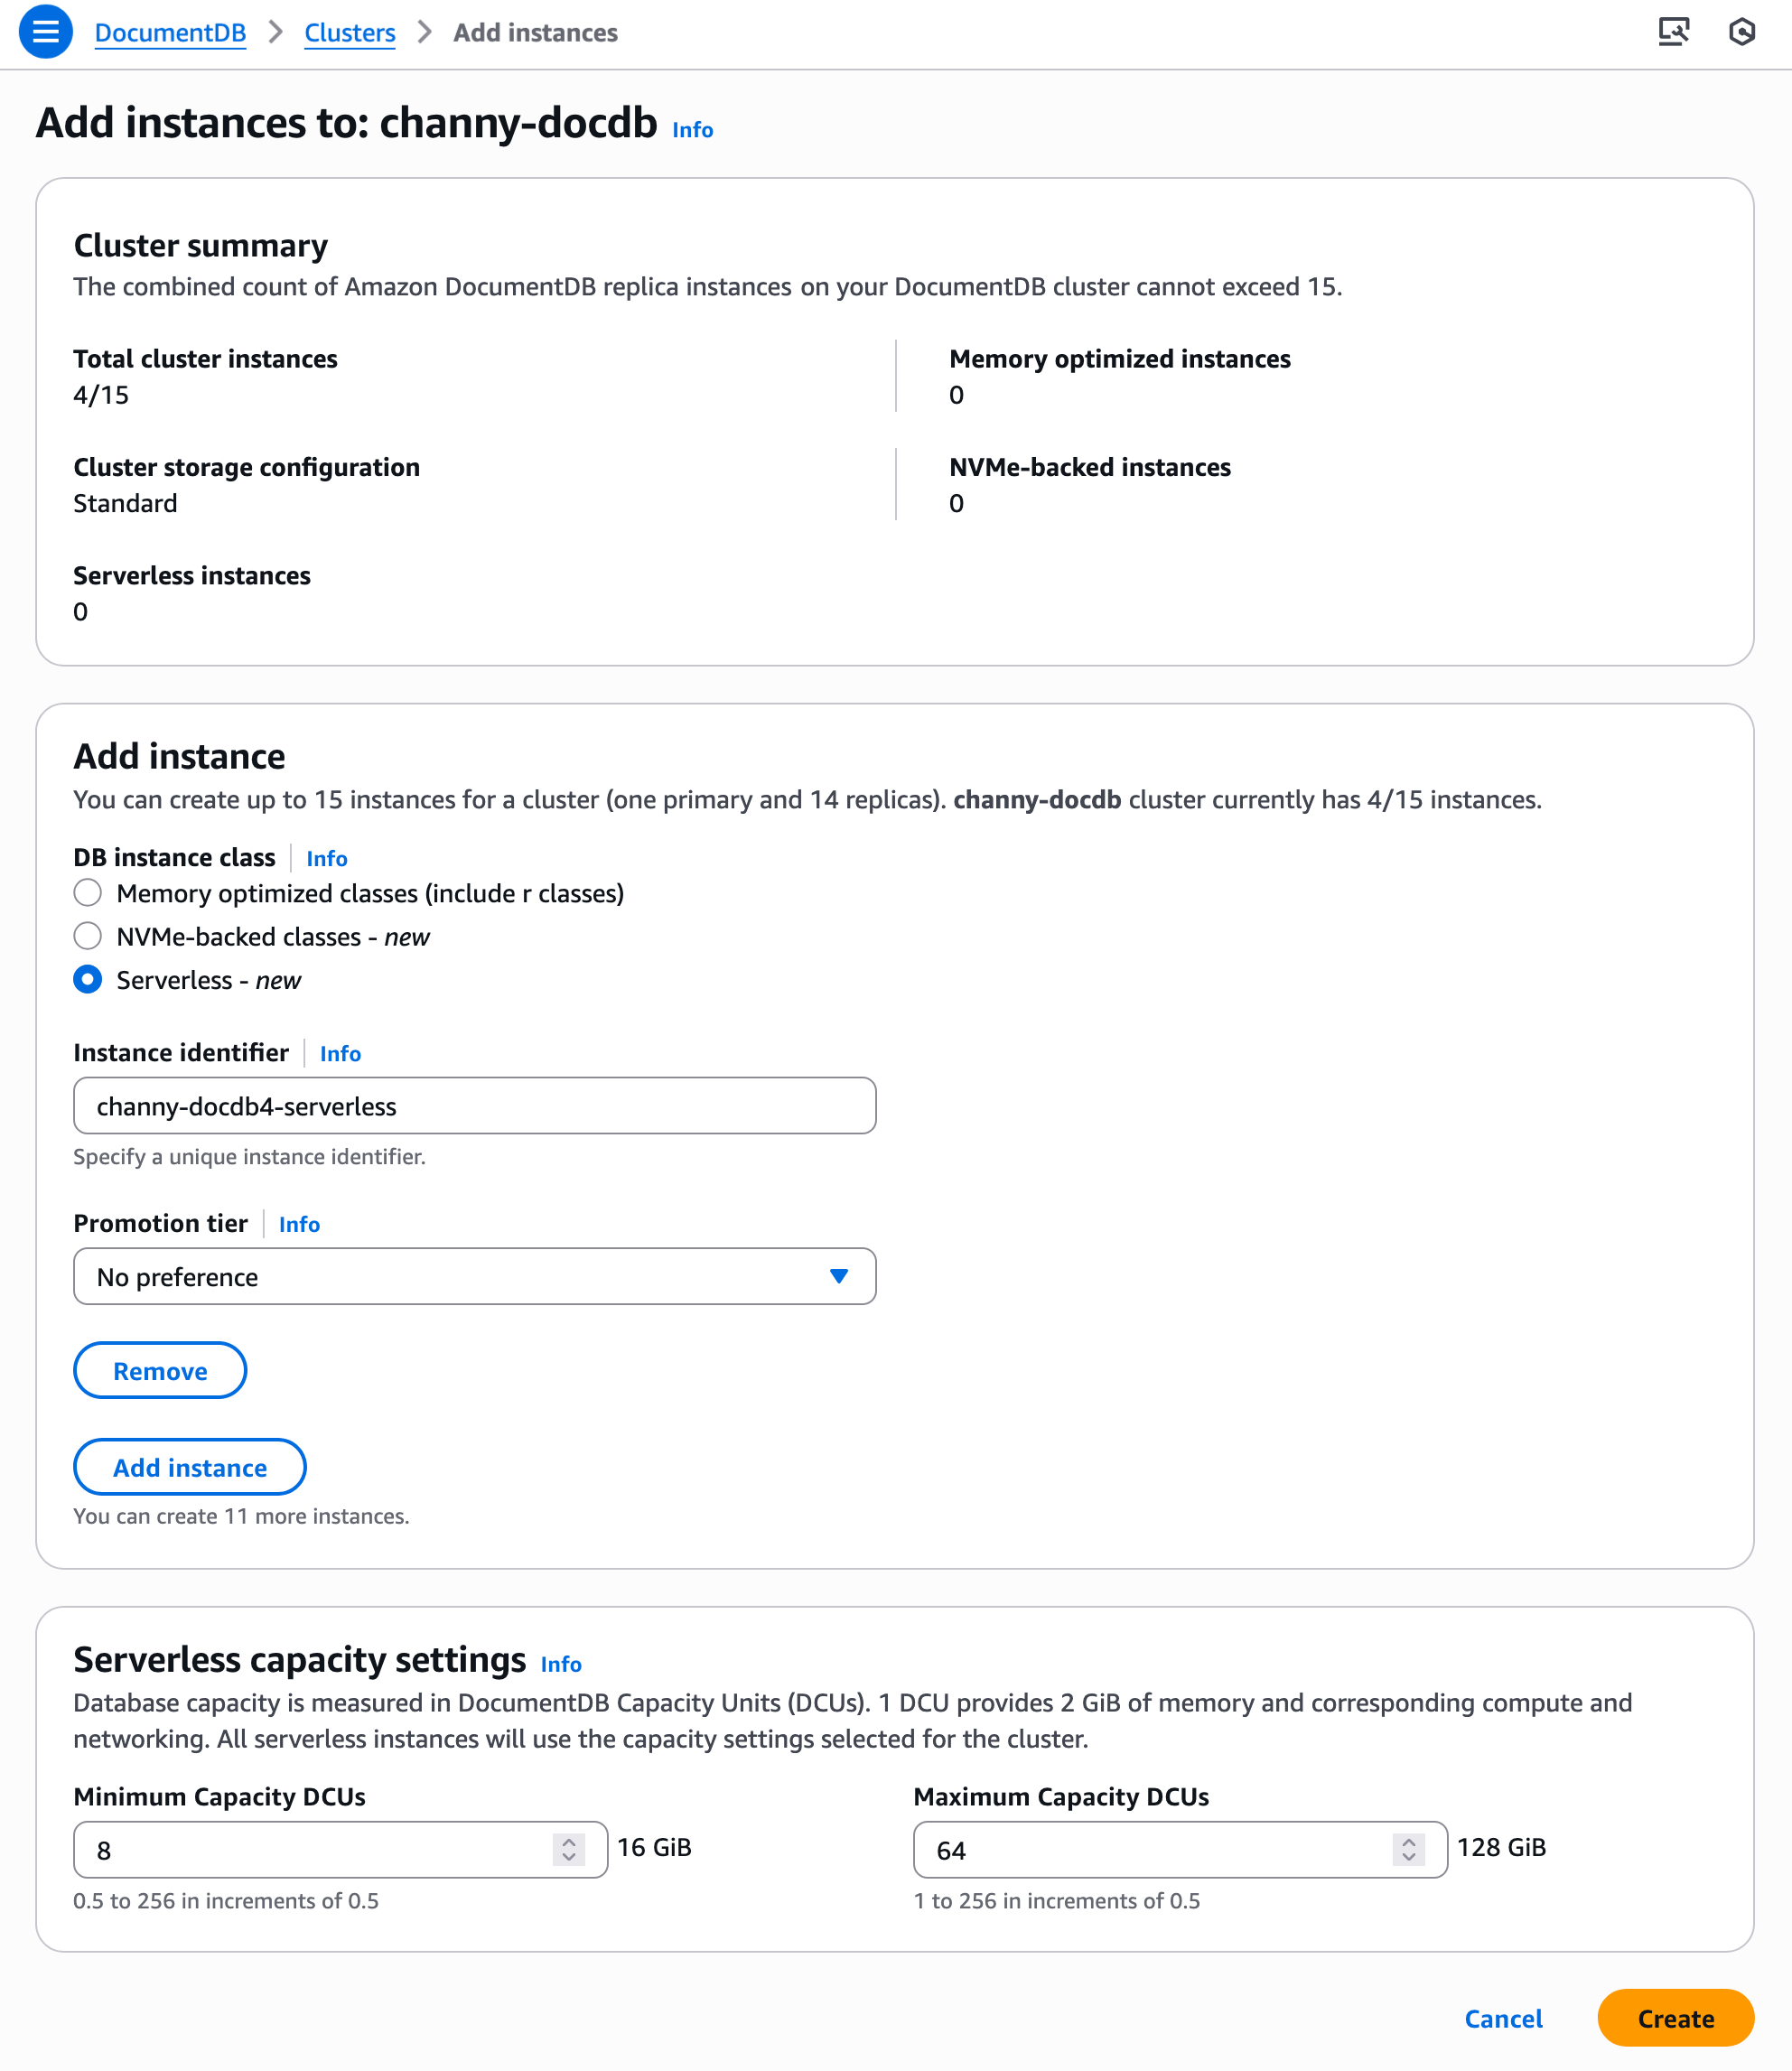
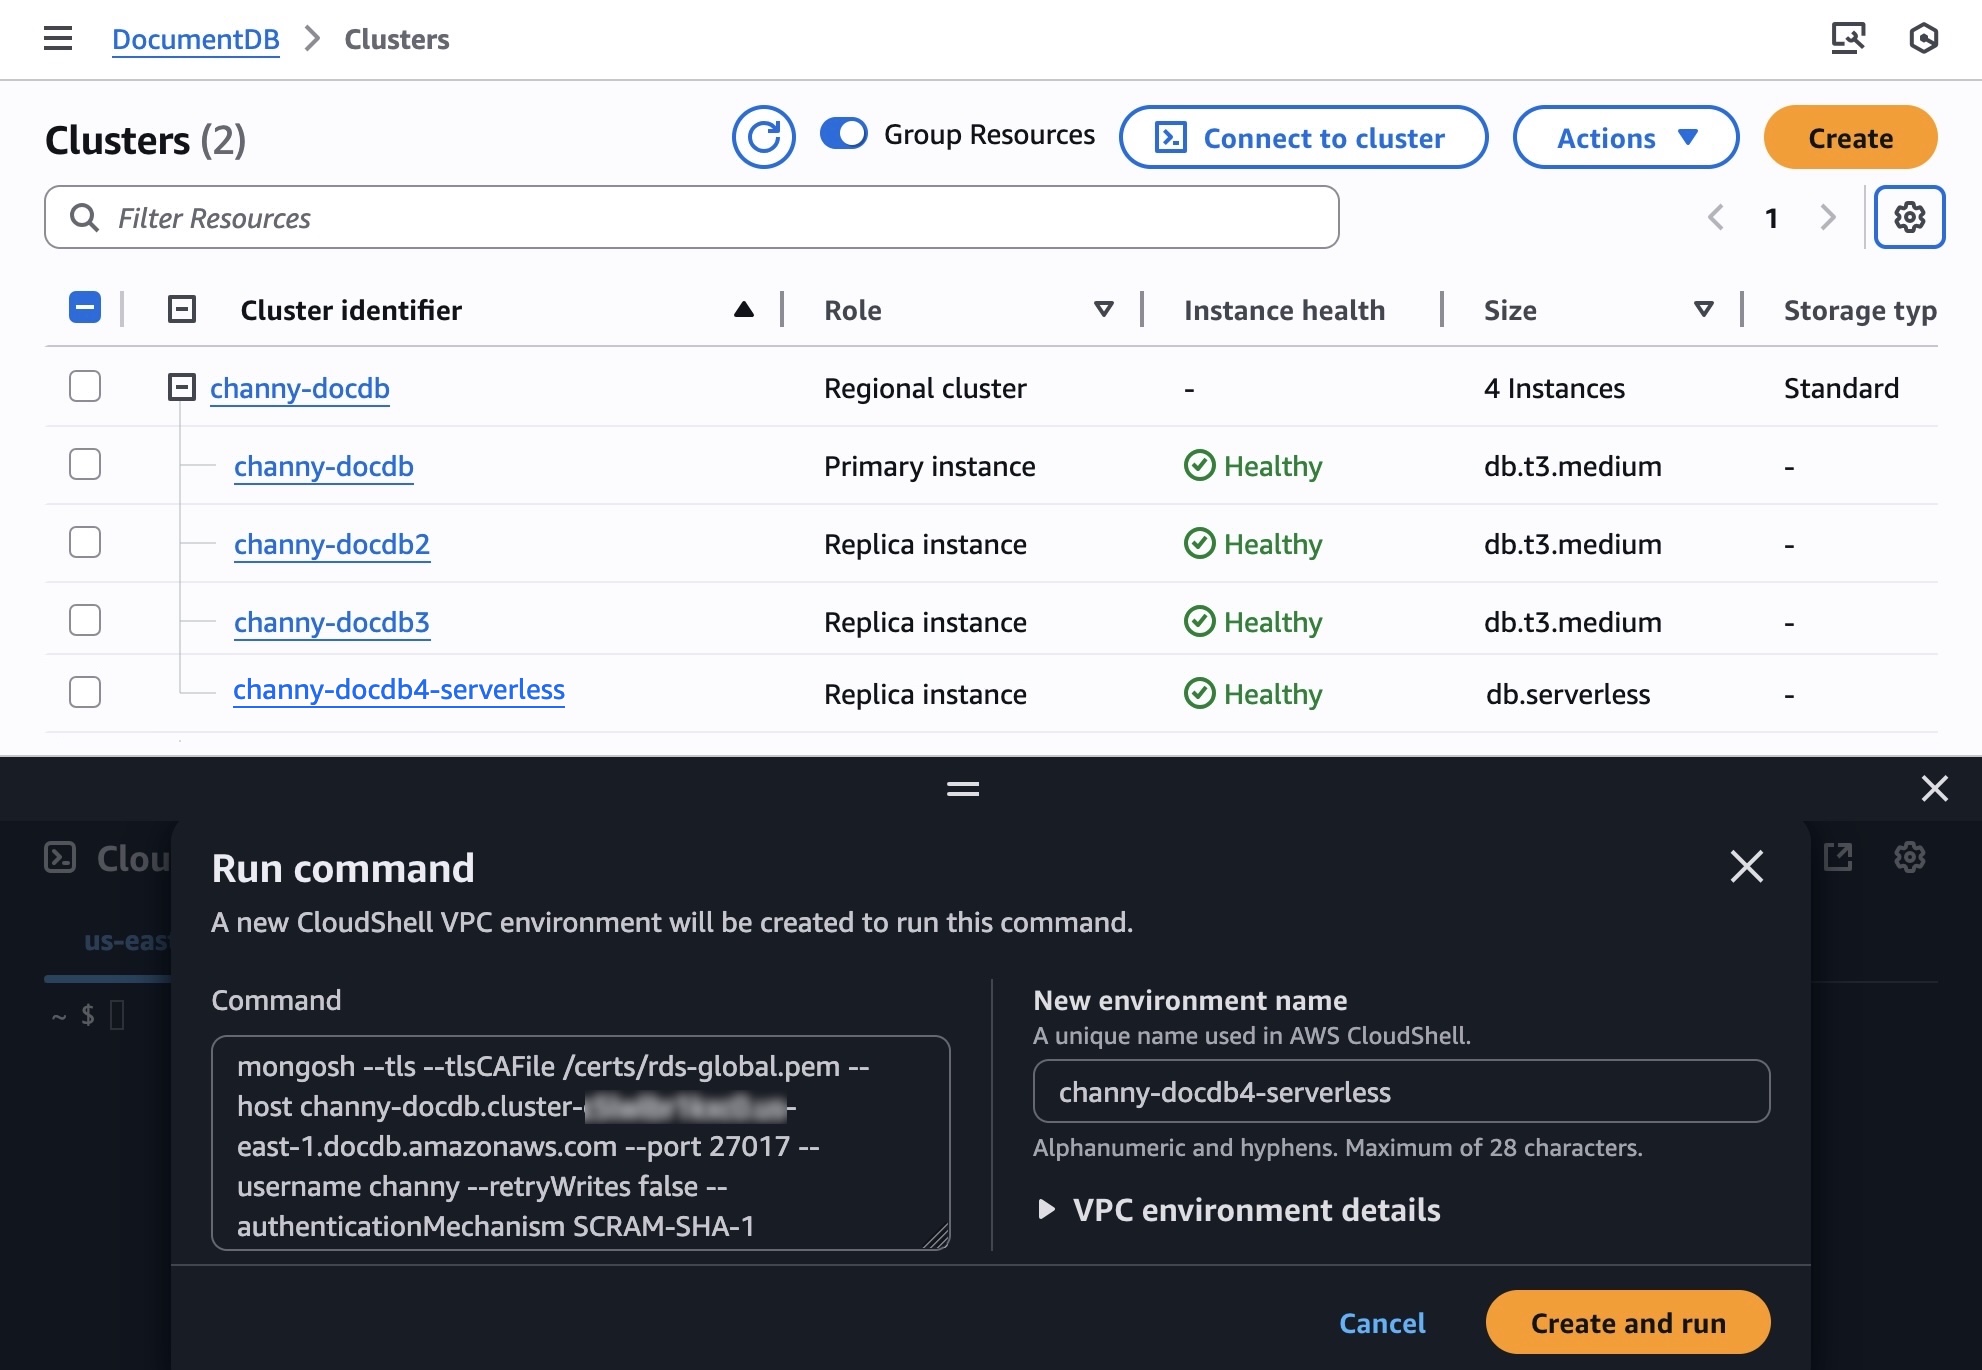
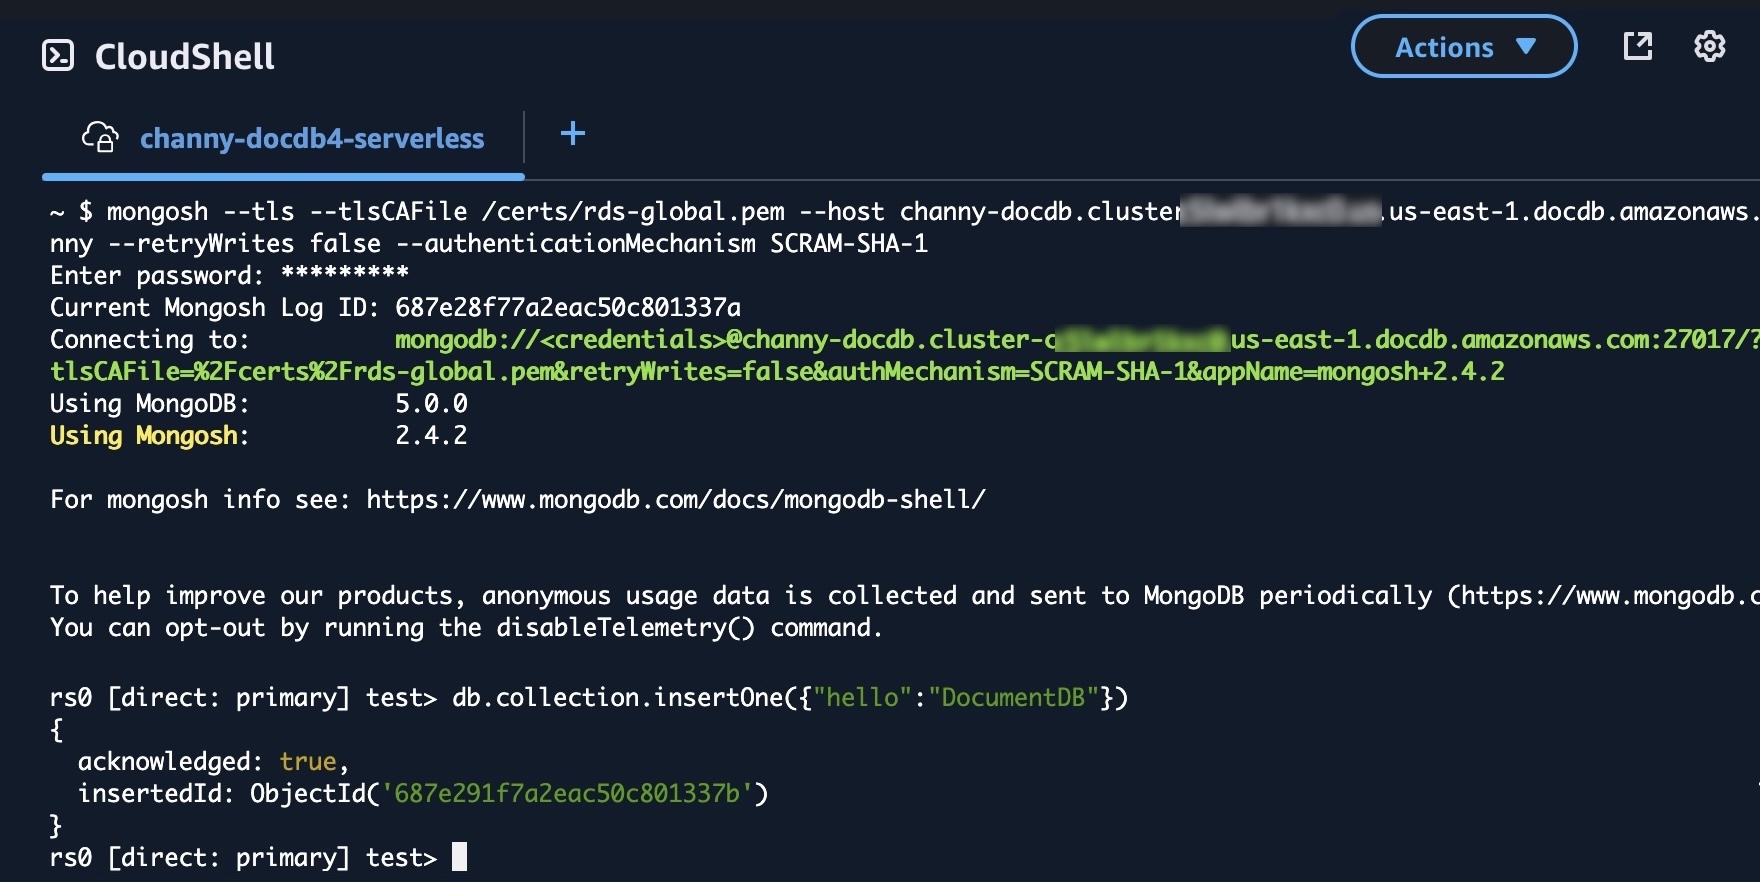
 Martin Milenkoski is a Software Development Engineer on the Amazon Redshift team, currently focusing on data lake performance and query optimization. Martin holds an MSc in Computer Science from the École Polytechnique Fédérale de Lausanne.
 Kalaiselvi Kamaraj is a Sr. Software Development Engineer on the Amazon Redshift team. She has worked on several projects within the Amazon Redshift Query processing team and currently focusing on performance related projects for Amazon Redshift DataLake and query optimizer.
 Jonathan Katz is a Principal Product Manager – Technical on the AWS Analytics team and is based in New York. He is a Core Team member of the open-source PostgreSQL project and an active open-source contributor, including to the pgvector project.