Post Syndicated from Home Assistant original https://www.youtube.com/shorts/qoWro9wi03Q
How Democrats Could Rein in the Iran war
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/Xa5zeJ9khrE
Build a multi-team AI and analytics environment on Amazon SageMaker Unified Studio with Terraform
Post Syndicated from Harshi Surampalli original https://aws.amazon.com/blogs/big-data/build-a-multi-team-ai-and-analytics-environment-on-amazon-sagemaker-unified-studio-with-terraform/
Platform engineers who support data and AI teams face a recurring challenge: analytics, machine learning (ML), and AI developer teams each need different tools. When each team operates its own tools and infrastructure, governance becomes fragmented. Organizations face duplicated effort and limited collaboration. Data engineers, data scientists, and AI developers might all work with the same underlying data. Yet they navigate separate consoles, manage distinct AWS Identity and Access Management (IAM) configurations, and lack a shared view of each other’s work.
Amazon SageMaker Unified Studio brings these capabilities together in one governed workspace. Every practitioner gets access to the tools they need: SQL editors, JupyterLab notebooks, and the Amazon Bedrock IDE. At the same time, they share a common business data catalog, security model, and project structure, all governed centrally within Amazon SageMaker Unified Studio. Teams collaborate within projects, while access to data, compute, and development artifacts is managed centrally.
Setting up this kind of multi-team environment means coordinating IAM roles, blueprints, project profiles, and user onboarding on top of the initial domain configuration. New user roles and use cases might require enabling new blueprints and combining them into new project profiles to extend the functionality supported by the domain. To keep this repeatable and consistent, we use the Amazon SageMaker Unified Studio Terraform module to codify the entire setup. The module creates three purpose-built project profiles, one for each team, on a shared domain, plus an initial project to get you started. Creating the remaining per-team projects is a single additional sub-module block.
Consider a mid-size technology company with three teams that need cloud-based data and AI capabilities:
| Team | What they need | Key AWS services |
| Data Analytics | Query and transform data across Amazon Simple Storage Service (Amazon S3), Apache Spark jobs, and Amazon Redshift, build and orchestrate data pipelines, manage a data catalog | Amazon SageMaker Lakehouse, Amazon Redshift Serverless, AWS Glue, Amazon Managed Workflows for Apache Airflow (MWAA) |
| Machine Learning | Run experiments, train models, deploy endpoints | Amazon SageMaker AI, MLflow, Amazon EMR Serverless |
| Generative AI | Build chat agents, knowledge bases, prompt flows, and guardrails | Amazon Bedrock |
A common issue today is that customers don’t have a unified strategy to deploy and manage their infrastructure. The analytics team has a standalone Amazon Redshift cluster, the ML team provisions SageMaker notebooks ad hoc, and the generative AI team experiments with Bedrock through the console. Each team runs its own infrastructure. Because these environments are separate, there’s no shared data catalog, no consistent access control, and no central visibility into what’s running or what it costs.
The goal: a single unified environment where each team gets exactly the capabilities they need, with shared data access, consistent security, and infrastructure you define entirely as code.
Solution overview
We use the Amazon SageMaker Unified Studio Terraform module to create a single domain with three project profiles, one per team. A project profile is a collection of blueprints which are configurations used to create projects, while the domain provides shared governance, IAM roles, and networking.
Key module capabilities:
- Dual provider: Uses both the AWS provider and AWS Cloud Control (AWSCC) provider for full Amazon SageMaker Unified Studio resource coverage.
- Service role flexibility: All IAM roles are auto-created with least-privilege policies, or you can supply existing roles to be used by Amazon SageMaker Unified Studio.
- Domain and project level access using AWS Identity and Access Management (IAM), single sign-on (SSO) with AWS IAM Identity Center or both.
- KMS encryption: Optionally encrypt domain metadata with a customer-managed AWS Key Management Service (AWS KMS) key using
kms_key_identifier. - Model governance: The domain module automatically provisions a model governance project for Generative AI administrators to be added to. Members of the project can enable or disable specific models accessible in the domain.
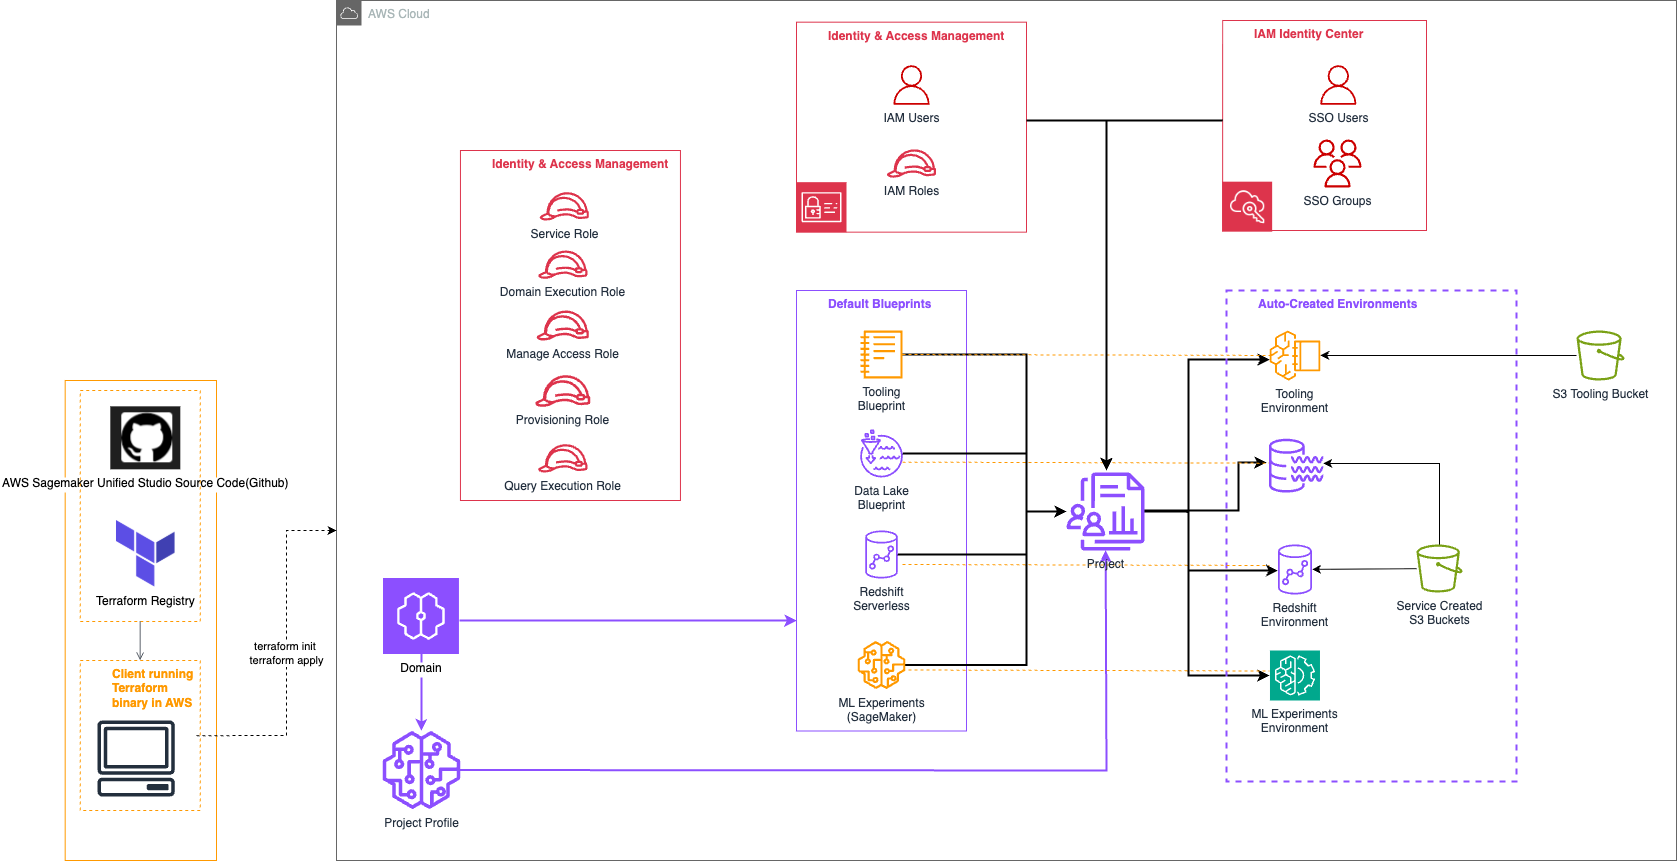
Figure 1: Multi-team Amazon SageMaker Unified Studio architecture
The Terraform module follows a layered architecture with four composable modules:
Layer 1: Domain module. Creates the domain, Tooling blueprint, IAM roles, and S3 bucket:
Layer 2: Blueprint module. Enables individual blueprints on the domain using for_each:
Layer 3: Project profile module. Composes blueprints into team-specific profiles:
Layer 4: Project and Project membership module. Creates a project and assigns members:
At a high level, the deployment mentioned in this post performs the following:
- Terraform creates the Amazon SageMaker Unified Studio domain with shared IAM roles and networking.
- Terraform enables all required blueprints on the domain (DataLake, RedshiftServerless, Bedrock services, EMR, and so on).
- Terraform composes three project profiles (one per team), selecting the appropriate blueprints and parameters.
- Terraform creates a project from the first available profile (All Capabilities profile).
- Project members (SSO users, SSO groups, IAM users, or IAM roles) are assigned as owners or contributors to the created project.
What each team gets
After deployment and teams are assigned to their respective projects, each team can:
- Data Analytics team (SQL Analytics profile):
- Query data across Amazon S3 and Amazon Redshift using SageMaker Lakehouse.
- Manage a shared data catalog with AWS Glue.
- Create and share SQL notebooks and dashboards.
- Machine Learning team (All Capabilities profile):
- Run ML experiments with MLflow integration.
- Process data at scale with Amazon EMR Serverless.
- Access all SQL analytics and generative AI capabilities.
- Build end-to-end ML pipelines with Workflows.
- Generative AI team (Generative AI profile):
- Build chat agents and knowledge bases with Amazon Bedrock.
- Create and test prompt flows and guardrails.
- Evaluate model performance with Bedrock Evaluation.
- Deploy serverless AI functions.
All three teams share the same governed domain, data catalog, IAM policies, and networking. This eliminates the silos that existed before. Team isolation is achieved by assigning users or groups to projects created from the appropriate project profile.
Prerequisites
Before you begin, verify the following:
- An AWS account with permissions to create and manage Amazon DataZone, AWS Identity and Access Management (IAM), Amazon Simple Storage Service (Amazon S3), Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Virtual Private Cloud (Amazon VPC) resources. See Changing permissions for an IAM user for guidance.
- Terraform version >= 1.7.
- AWS Command Line Interface (AWS CLI) configured with credentials that have access to the target account and AWS Region.
- Amazon SageMaker Unified Studio available in your target Region.
- AWS IAM Identity Center configured (required only if using SSO-based project membership). If using IAM-only membership, Identity Center isn’t required.
Solution walkthrough
We complete the setup in four steps:
- Clone the module repository.
- Configure the Terraform variables for each team.
- Apply the Terraform configuration.
- Verify the platform and onboard teams.
Step 1: Clone the repository
Clone the Amazon SageMaker Unified Studio Terraform module and navigate to the quick-setup example:
The module directory structure:
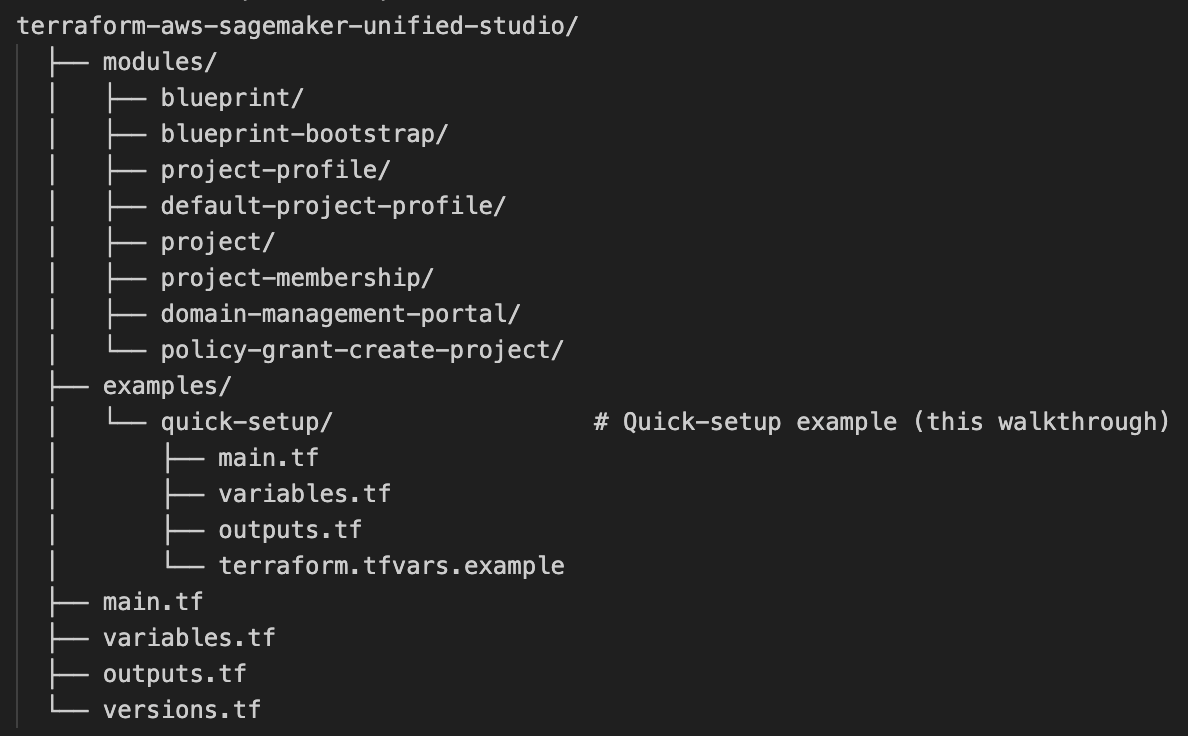
Figure 2: Directory structure of the Amazon SageMaker Unified Studio Terraform module
Change into the quick-setup example directory:
Step 2: Configure the Terraform variables
Copy the example variables file and edit it:
For our multi-team scenario, we enable all three project profiles:
Here’s what each profile creates:
| Variable | Team | Blueprints enabled |
enable_sql_analytics |
Data Analytics | DataLake, LakehouseCatalog, RedshiftServerless |
enable_generative_ai |
Generative AI | BedrockChatAgent, BedrockEvaluation, BedrockFlow, BedrockFunction, BedrockGuardrail, BedrockKnowledgeBase, BedrockPrompt |
enable_all_capabilities |
ML (full access) | All of the preceding + EMR Serverless, EMR on EC2, MLExperiments, Workflows |
Internally, the toggles build a dynamic map of blueprints that gets passed to the blueprint module’s for_each:
Network auto-discovery: If you don’t specify vpc_id and subnet_ids, the module automatically discovers and uses your default VPC and its subnets.
Customizing blueprint parameters: The quick-setup example uses recommended defaults. For production, you can customize Amazon Redshift capacity, Glue database names, or deployment modes in the sql_analytics_blueprint_config and generative_ai_blueprint_config locals in main.tf. For example, to increase Redshift Serverless max capacity:
Step 3: Apply the Terraform configuration
Configure your AWS CLI credentials for the target account and Region, then:
- Run
terraform initto download the modules and providers. - Run
terraform planand review the output to verify:- An Amazon SageMaker Unified Studio domain will be created.
- Three IAM roles will be created (domain execution, manage access, provisioning).
- An S3 bucket for tooling storage will be created.
- All selected blueprints will be enabled on the domain.
- Three project profiles will be created (SQL Analytics, Generative AI, All Capabilities).
- A project will be created from the first available profile.
- Project memberships will be configured for SSO identities, IAM principals or both.
- Run
terraform applyand allow the apply to complete.
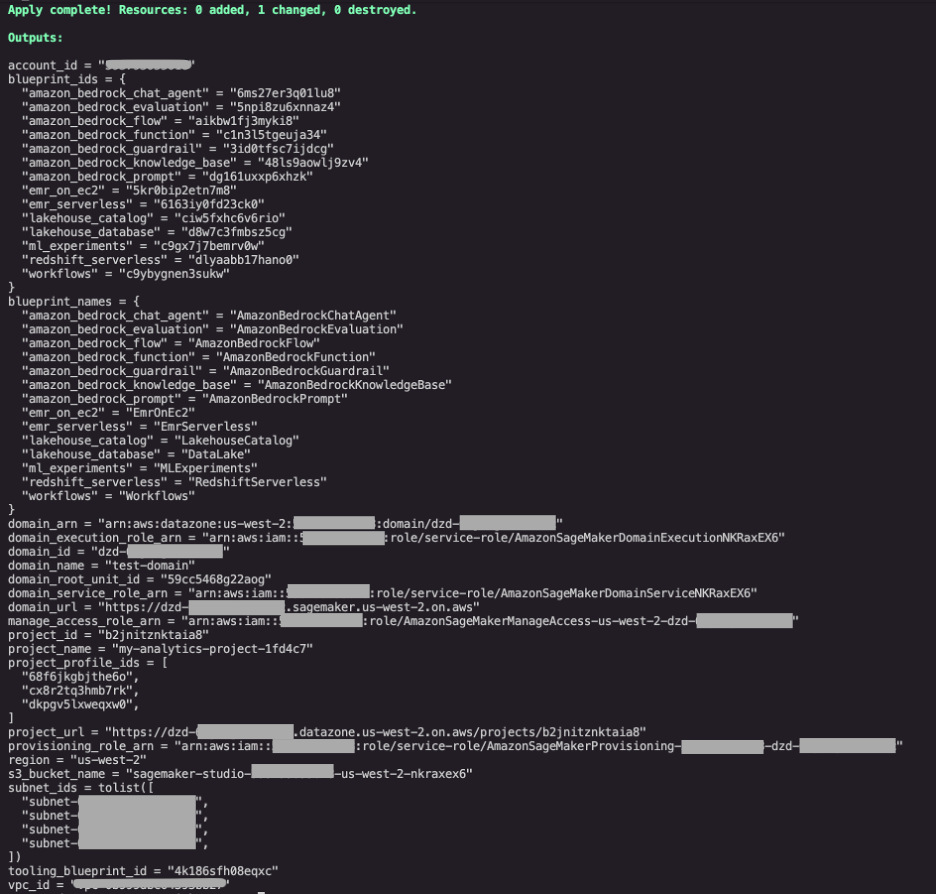
Figure 3: Successful terraform apply output showing the domain URL, project ID, and project profile IDs
View the key outputs:
Step 4: Verify the platform and onboard teams
Verify the deployment. Confirm the environment is healthy before onboarding teams:
- Open the
domain_urlfrom the Terraform output and confirm the Amazon SageMaker Unified Studio portal loads, and you can sign in using a principal that was added to the project. - In the portal, confirm the three project profiles (SQL Analytics, Generative AI, All Capabilities) appear under the domain.
- Confirm the initial project created by
terraform applyis listed and project members can access the project interface. - Cross-check the Terraform outputs (
terraform output blueprint_ids,terraform output project_profile_ids) against the blueprints and profiles you expected.
Access the portal: Open the domain_url from the Terraform output. Any user added as an owner or member of the project can sign in immediately and access their project.
Create team-specific projects: The initial terraform apply creates one project. To create additional projects for each team, add more "project" sub-moduleblocks referencing different profiles:
You can also create projects from the Amazon SageMaker Unified Studio portal using the available profiles.
Onboard additional users: To isolate teams, create separate projects using the appropriate project profiles as shown earlier, then add members (SSO users, SSO groups, IAM users, or IAM roles) to each project using the project_membership module. Each principal type can be used independently or in combination. This restricts each team to the capabilities defined by their project profile. For details on adding IAM principals, see the next section.
Adding IAM principals to projects
Amazon SageMaker Unified Studio uses project membership to control who can access a project’s resources (data, environments, and development artifacts). The Terraform module supports four principal types for project membership:
- SSO users: Individual IAM Identity Center users.
- SSO groups: IAM Identity Center groups (all members inherit access).
- IAM users: Native IAM user ARNs.
- IAM roles: IAM role ARNs (assumed by humans, services, or automation).
Project membership defines which principals are authorized to access a project. It also sets what actions they are allowed to perform as either project owners or contributors. When a principal is added to a project through project membership, they are automatically added to the domain membership list and are authorized to access the interface.
Why add IAM principals to projects?
While Identity Center users and groups cover most human access patterns, IAM principals unlock additional use cases:
| Use Case | Principal Type | Example |
| Continuous integration and continuous delivery (CI/CD) pipeline deploys environments in a project | IAM Role | arn:aws:iam::123456789012:role/GitHubActionsDeployRole |
| Service account runs automated data pipelines | IAM Role | arn:aws:iam::123456789012:user/etl-service-account |
| Organization without Identity Center needs project access | IAM User/Role | Any IAM principal in the account |
Configuration
The project_owners and project_contributors variables accept any combination of principal types:
Project members can be defined as owners or contributors. The AWS caller identity that runs this Terraform code is added as a project owner so that it has permission to manage project resources and update team membership. To know what permissions each of these roles have please refer to the full documentation here.
How the module registers principals
The module automatically creates the required domain-level profile for each principal before assigning membership. No manual pre-registration is needed. The module handles the full lifecycle.
IAM identity prerequisite: IAM roles and users must have the AWS managed SageMakerStudioUserIAMConsolePolicy (or equivalent) attached to access the Amazon SageMaker Unified Studio interface. This policy provides permissions for domain listing, project creation, and other portal operations. The module doesn’t automatically attach this policy to IAM roles.
Example: Granting a CI/CD pipeline access to a project
The pipeline role can now create and manage environments within the project scope, without domain-wide access.
Example: IAM-only project membership
Organizations that don’t use Identity Center can manage project membership entirely through IAM principals by setting enable_sso = false in the domain module.
Note: Currently, only IAM principals within the same AWS account as the domain can access the Amazon SageMaker Unified Studio portal. Cross-account IAM role access might be limited. Verify cross-account support in your Region before relying on it for production access patterns.
Additional considerations
As you move this setup toward production, consider the following areas.
Scaling to multiple environments
For production readiness, deploy separate domains for development, staging, and production using Terraform workspaces or separate state files:
Cost management
The base infrastructure (domain, IAM roles, S3 bucket) has minimal ongoing costs. Primary charges occur when teams create and use environments:
- Redshift Serverless: Pay per RPU-hour when queries are running.
- EMR Serverless: Pay per vCPU and memory per second.
- Bedrock: Pay per input and output token.
- S3: Standard storage pricing.
Use the parameter_overrides in blueprint configurations to set capacity limits (for example, redshiftMaxCapacity) and control costs.
Security and governance
The module creates least-privilege service roles by default. For additional permissions, attach custom policies to the user role:
You can also configure VPC endpoints for private connectivity and enable AWS CloudTrail for audit logging of all Amazon DataZone API calls.
DevOps best practices
- Version control: Store configurations in a code repository with automated CI/CD pipelines.
- Module registry: Publish organization-specific module compositions to a private Terraform registry.
Cleanup
To destroy all resources:
Warning: This deletes all resources including the domain, projects, and any data stored in the S3 bucket. Additionally, extra resources created manually within the console won’t be affected by this terraform destroy.
Conclusion
In this post, we walked through a real-world scenario: building a multi-team AI and analytics unified environment where data analysts, ML engineers, and generative AI developers each get tailored capabilities on a shared, governed domain. Terraform provisions and manages the full set of Amazon SageMaker Unified Studio resources, including the domain, blueprints, project profiles, and an initial project. As your needs grow, you can extend the configuration by adding projects per team through the project sub-module.
Key benefits of this approach:
- Team-specific profiles: Each team gets exactly the blueprints they need, nothing more.
- Shared governance: One domain, one set of IAM roles, one data catalog, consistent policies.
- Infrastructure as Code: Repeatable, auditable, version-controlled deployments.
- Auto-discovery: Minimal configuration required; VPC, subnets, and instance details are discovered automatically.
- Scalable: Add teams, environments, or accounts by extending the same Terraform configuration.
- Flexible membership: Add SSO users, IAM users, IAM roles, or any combination as project members.
The Terraform module and examples are available in the Amazon SageMaker Unified Studio Terraform module repository.
Have questions or feedback? Leave us a comment or open an issue in the GitHub repository.
Additional resources
- Amazon SageMaker Unified Studio documentation
- Amazon SageMaker Unified Studio Terraform module
- Authorization in Amazon SageMaker Unified Studio
- Terraform by HashiCorp
- Automate Amazon S3 File Gateway on Amazon EC2 with Terraform
About the authors
Ease of use and secure defaults in the new AWS experience
Post Syndicated from Keshav Narsipur original https://aws.amazon.com/blogs/security/ease-of-use-and-secure-defaults-in-the-new-aws-experience/
Starting on Amazon Web Services (AWS) is now more straightforward and more secure by default than it’s ever been. Over the past several months, we rolled out a new AWS experience that changes how you start building. It brings together a set of sensible, secure defaults, and taken one at a time, it’s easy to miss the bigger picture of what we’re building and why.
When we first built how you get started on AWS, cloud was a new concept. It was a world where RSS and APIs were the exciting new thing. Twenty years later, we’ve come a long way and learned a lot about how people start, build, and grow on AWS.
So, before I get into the recent launches, let me state the vision plainly: Make AWS straightforward to start on without giving up the depth, the pricing, or the security that make it the right place to grow. You shouldn’t have to choose between getting started quickly and staying secure. The rest of this post builds out this idea and highlights the defaults that make it real.
What developers told us
For years, developers have told us a version of the same thing. They knew AWS was where they wanted to grow, but they wanted to start fast, not plan for scale on day one. The same depth that lets AWS grow with you also meant more to set up on day one. There’s a payment method to enter before you can start, a console built for experienced administrators to get oriented in, and permissions to configure before your app can run. That feedback is fair, and it’s a big part of why we keep building a better AWS. The new experience is our answer to that, and most of it comes down to sensible, secure defaults.
The secure defaults behind the new experience
The new AWS experience sets secure defaults for you, so your setup starts secure instead of something you harden later. The defaults are sensible ones, drawn from what we’ve learned about how people start on AWS. Here are a few and what they do:
Builder ID sign-in, with two-factor protection built in. In the early days of AWS, you signed in as the account’s root user. You could set up separate identities for everyone, but that took real effort, so sharing one login was often the path of least resistance. We’ve learned a lot since then. AWS Builder ID is a personal identity that represents you as an individual, and you use it to sign in with email and password or through a social login like Google or Apple. When you start working with others, each person signs in with their own Builder ID rather than sharing one set of credentials, so access is tied to a person, not passed around. It’s the straightforward path rather than the hard one. In addition to that, you can register multi-factor authentication (MFA, an authenticator app or security key) that applies to whichever sign-in method you choose. This used to require deliberate setup. Now it’s there from the start.
A managed organization with AWS Organizations doing the heavy lifting behind the scenes. The starting flow is straightforward: you sign up and land in a project where you can start building right away. What I find interesting is what’s happening underneath. A project is more than an account. It pairs an account with its own spend limit and its own set of collaborators, so each project is a self-contained boundary with access scoped to just the people you invite. Rather than dropping you into a bare account, AWS creates and manages an organization for you, with your project as a member account inside it, and sensible guardrails already in place. As you grow, you add more projects—each its own member account—when you have work that needs its own budget or collaboration boundary, like a personal experiment kept separate from the beta you’re putting in front of your first users. This is the structure experienced teams land on eventually, usually after learning the hard way that putting resources with different budget or collaboration boundaries in the same account is tough to unwind later. The difference is we create the organization that enables this best practice for you from the start, so you’re set up for success well beyond day one without having to design or operate any of it yourself. When you’re ready for full control, you can activate advanced features in a single step and take over the organization directly, with no migration or downtime.
A data perimeter that grows with you. This is another default that I really want people to notice. You start with a foundational data perimeter already in place, restricting access to your resources from principals outside your organization. It’s a secure starting point rather than the complete, multi-dimensional data perimeter a larger organization would eventually build out. But the direction is that your security boundary should grow with you as you succeed on AWS, and here a brand-new developer gets that baseline automatically, without knowing the term or writing a line of policy.
A single AWS Region by default. Your resources run in one home Region to start, assigned when you sign up (aside from the handful of AWS services that are global by nature). That keeps your footprint simple and predictable: a smaller surface to secure and reason about, and a clear answer to where your data lives. When you need to operate more broadly, you can activate advanced features.
Spend limits that put you in control. You can set a hard spend limit on a project, starting at $20 a month, with notifications as you approach it. If a project reaches its limit, AWS pauses it rather than letting charges keep climbing, and you decide whether to raise the limit and resume. For an individual developer or a small team, that means no surprise bills: you set the ceiling, and no charges accrue past it without your say-so. You stay in control, and you can think big knowing the guardrails are already in place. A spend limit can also serve as an early signal. Unexpected spend is a classic indicator of inappropriate access or a runaway process, and because the project pauses at the ceiling you set, it also caps how far a cost surprise can go.
Roles set up for you, so IAM isn’t step one. As a new developer, you want to spend your early days building and experimenting, not wiring up IAM permissions. IAM Role Manager is on by default in the new AWS experience, so it creates and attaches the IAM roles your app needs as you build. Those roles start with the permissions an app typically needs to call other AWS services, enough to get you moving, not meant to last forever. As your app matures and tightening permissions matters, you take those roles over and right-size them, and by then you’ll know exactly what it needs. You focus on your app, AWS handles the plumbing.
Why the foundation matters
Starting from a secure base changes things in two ways. For you, it means the environment you start in is the one you keep. When you’re ready to scale, you grow it rather than building a new one. For us, it means secure by default is something we can keep extending, because a structured, secure starting point gives us a place to add to. We’re able to turn on additional governance controls as a natural part of the experience. One example we’re already working on is setting account-level Amazon S3 Block Public Access protections for newly created environments. I’m not going to put a timeline here, but I want to be clear about the trajectory.
Building for security and ease of use
Ease of use and strong security are too often framed as opposites. Everything we’ve shipped here is an argument that they don’t have to be. You can give someone the fastest possible path to building something real and have that path be secure and cost-safe by default. The same experience makes the easy things easy, like connecting your coding agent in a single step or inviting a collaborator by email, without extra setup. Each of these is useful on its own, but they were all designed around the same idea, that the easy path and the secure path should be the same path.
If you’ve tried the new experience, I’d genuinely like to hear what resonated and what you’d want next, including how we can make activating advanced features feel more managed over time. If you haven’t yet, the fastest way to see these defaults in action is to create an account and start your first project. We’re listening.
How Samsung Ads federated Snowflake Iceberg tables using Amazon Cognito
Post Syndicated from Balaji Selva Rajan original https://aws.amazon.com/blogs/big-data/how-samsung-ads-federated-snowflake-iceberg-tables-using-amazon-cognito/
This post is co-written with Ajay Gunasekaran, ML Platform Engineer at Samsung Ads.
Samsung Ads, the advertising division of Samsung Electronics, keeps its feature data in Snowflake as Apache Iceberg tables. Its machine learning (ML) team trains large-scale models on Amazon SageMaker AI, serving programmatic buyers who reach Samsung Smart TV and connected TV audiences. Connecting the two usually means copying the data into Amazon Simple Storage Service (Amazon S3) on a schedule. That adds a second pipeline to operate, a second copy to store, and two sets of permissions to keep in agreement.
Instead of copying the data, a team can write the final pipeline stage as Snowflake-managed Iceberg tables in Amazon S3 and federate them into AWS Lake Formation. Amazon Cognito supplies the OAuth2 tokens that Snowflake trusts. Both applications then read one copy of the data in Amazon S3, with Snowflake managing the tables and the team using Lake Formation to control which principals can read them. Model engineers can choose the query engine that fits each training job, without duplicating data or maintaining a second pipeline.
In this post, we show you how to build the pattern Samsung Ads used. You federate Snowflake Iceberg tables into AWS Lake Formation with Amazon Cognito, then query them from Amazon Athena.
Solution overview
This solution federates the Snowflake Horizon Catalog into AWS Lake Formation, using Amazon Cognito to issue OAuth2 tokens for machine-to-machine authentication. AWS Glue connection runs inside an Amazon Virtual Private Cloud (Amazon VPC), reaching Snowflake through AWS PrivateLink and the Cognito token endpoint through a NAT gateway. AWS analytics engines then query Snowflake-managed Iceberg tables under Lake Formation governance, with no second copy of the tables to maintain. The following diagram shows the query path, from Amazon Athena through AWS Lake Formation and the AWS Glue connection to Snowflake and Amazon S3.
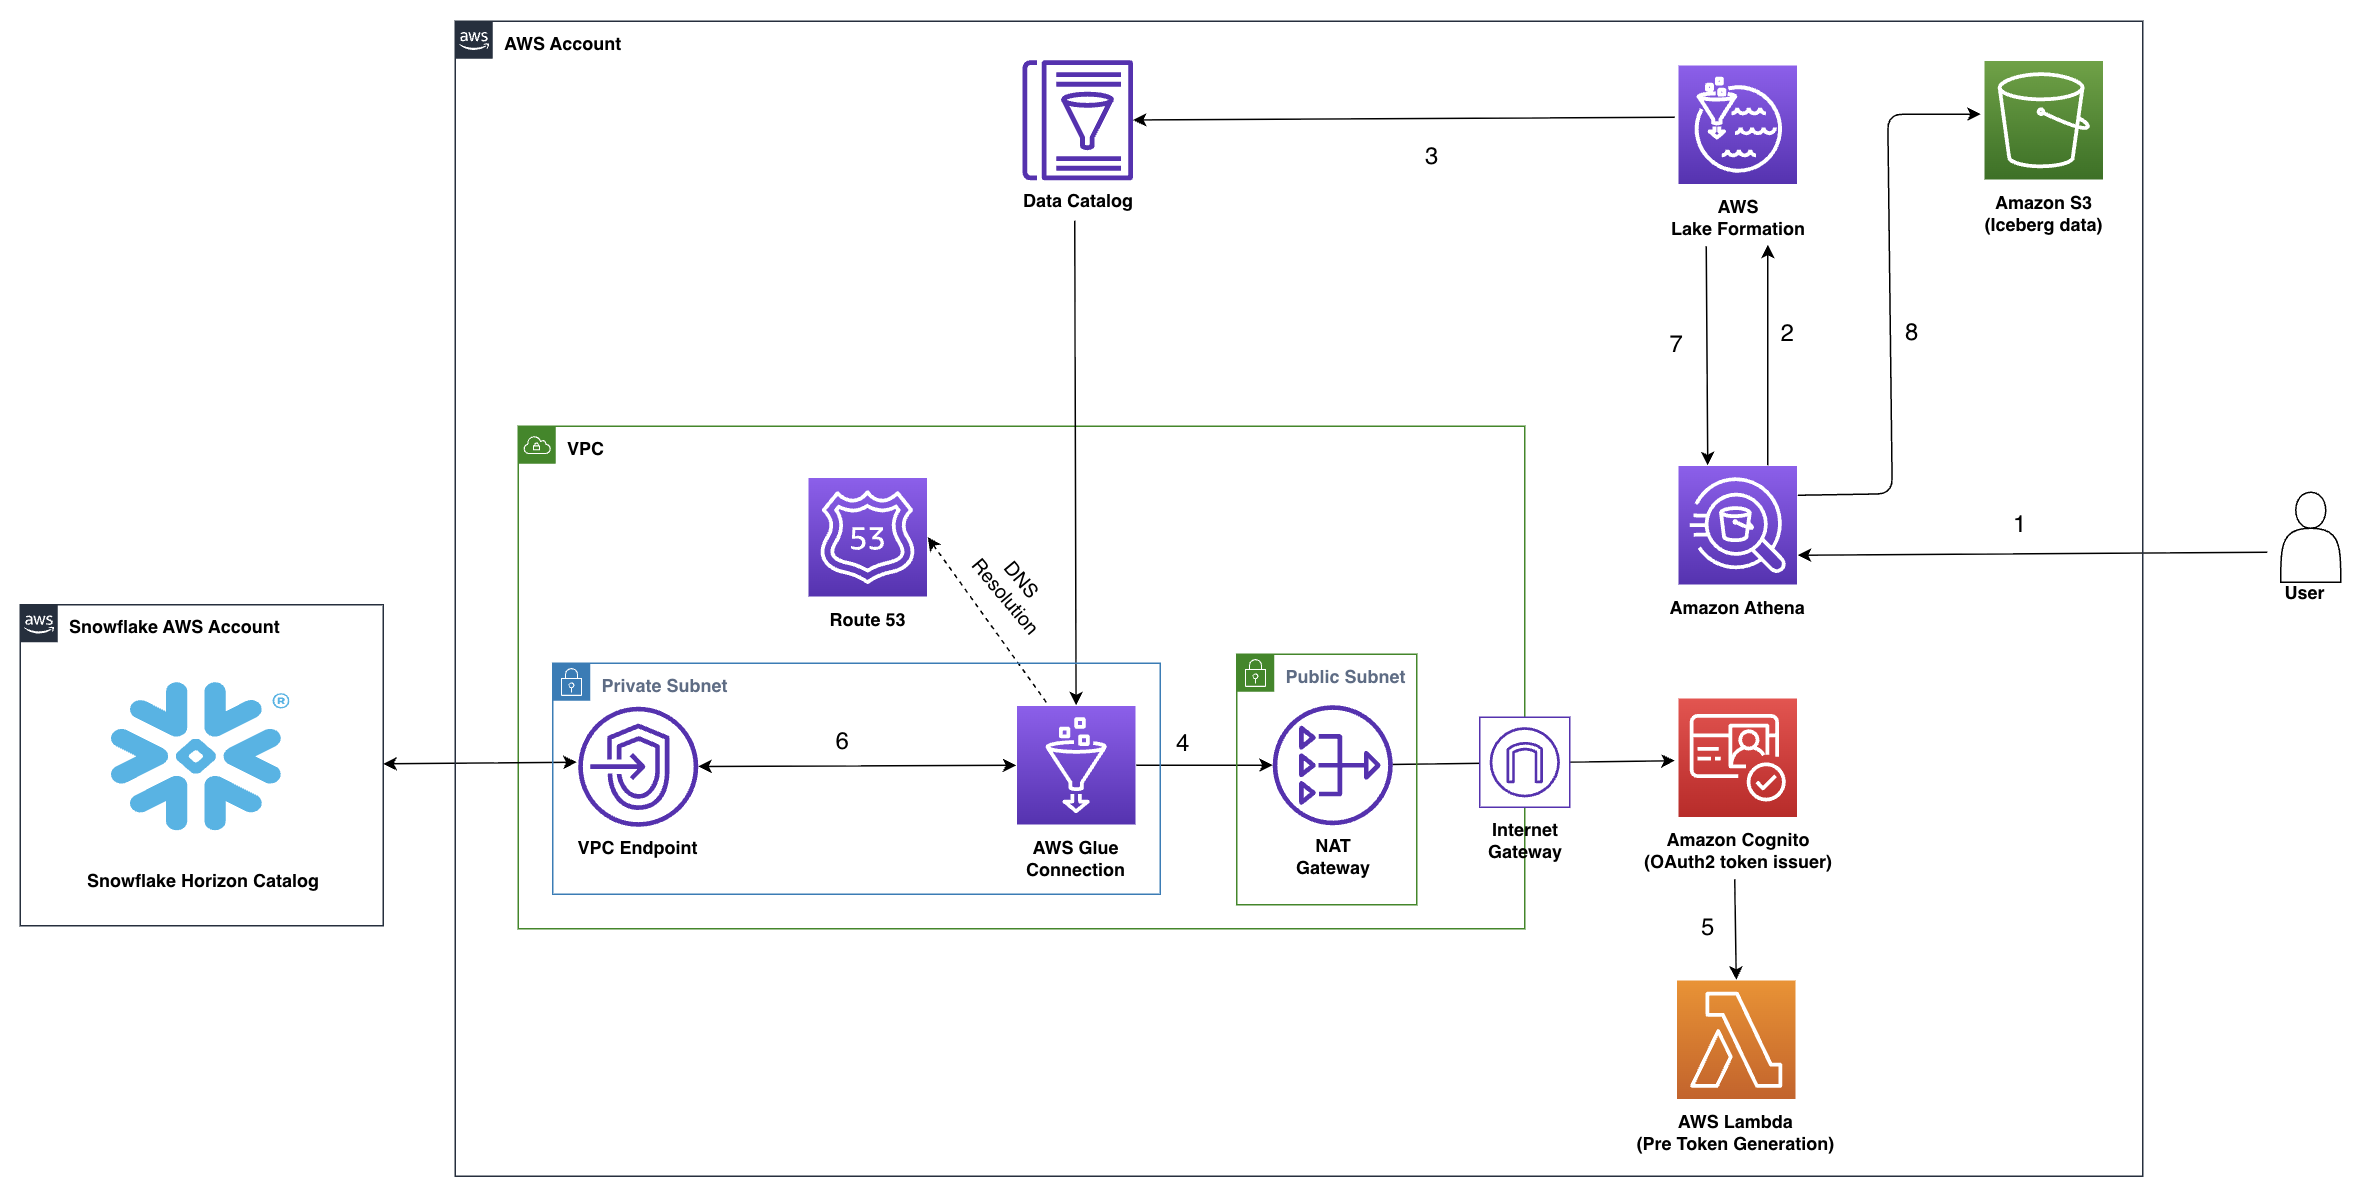
Figure 1: Architecture for Snowflake Horizon Catalog federation to AWS Lake Formation using Amazon Cognito
Here’s how the workflow runs:
- A user or application submits a SQL query in Amazon Athena that references a federated table in the Snowflake catalog.
- Athena delegates catalog resolution and permission checks to Lake Formation, which evaluates fine-grained access controls on the federated catalog entry.
- Lake Formation resolves the table reference through the AWS Glue Data Catalog, which holds the connection configuration for Snowflake and invokes the AWS Glue connection.
- AWS Glue connection runs in a private subnet. It sends a
client_credentialsrequest to the Amazon Cognito token endpoint with the client ID, client secret, andscope. The request leaves through the NAT gateway and internet gateway because the machine-to-machine token endpoint is public. - Amazon Cognito invokes the Pre Token Generation Lambda trigger (
V3_0), which adds theaudclaim that Snowflake External OAuth validation requires. Amazon Cognito returns the access token to the connection. - Using that token, AWS Glue connection calls the Snowflake Horizon Catalog Iceberg REST endpoint for table metadata. The response includes the schema and the location of the data files in Amazon S3. An Amazon Route 53 private hosted zone resolves the hostname, because the Snowflake endpoint service doesn’t provide private DNS. The request travels through the VPC endpoint over AWS PrivateLink.
- The connection returns the metadata to Lake Formation, which generates temporary, scoped Amazon S3 credentials and passes them to Athena.
- Athena uses those credentials to read the Iceberg metadata and Parquet data files from the registered Amazon S3 location, runs the query, and returns results.
Why Amazon Cognito
AWS Glue connection authenticates with the OAuth2 client_credentials grant, so providers Snowflake trusts that support that grant can issue the token. Samsung Ads chose Amazon Cognito for three reasons:
- Each table lookup against Snowflake depends on a token from the provider, so the team wanted to own it alongside the rest of the solution.
- An enterprise identity provider is typically administered by a central security team, so each new machine-to-machine client is a cross-team request. Owning the user pool makes it self-service.
- Each app client is a distinct machine identity, and the security integration trusts the user pool rather than an individual client. You can therefore serve several workloads from one integration, each with its own read-only Snowflake role.
Prerequisites
Before you begin, verify that you have the following:
- Snowflake account hosted on AWS in the same AWS Region where you create the AWS resources in this post, on the Business-Critical edition or higher, which AWS PrivateLink requires. Confirm the Region with
SELECT CURRENT_REGION();. You needACCOUNTADMINto create the security integration and to authorize PrivateLink.- Snowflake-managed Iceberg tables created in Snowflake Horizon Catalog using
CATALOG = 'SNOWFLAKE'with an external volume pointing to the S3 bucket. If you don’t have one, see Configure an external volume for Amazon S3 in the Snowflake documentation.
- Snowflake-managed Iceberg tables created in Snowflake Horizon Catalog using
- AWS account with an AWS Identity and Access Management (IAM) principal that has data lake administrator permissions in AWS Lake Formation. The principal also needs permissions to create IAM roles and policies, Amazon Cognito user pools, AWS Lambda functions, VPC resources, and AWS CloudShell. We use AWS Command Line Interface (AWS CLI) commands throughout this post.
- Amazon S3 bucket that holds your Snowflake-managed Iceberg data files.
- An AWS user with long-term access keys that you delete immediately after Step 4:
SYSTEM$AUTHORIZE_PRIVATELINKneeds a federation token from the long-term keys of an IAM user, becausests:GetFederationTokenrejects role-session credentials. Snowflake persists the authorization, so you can delete the key and the user afterwards and the federation keeps working.
Walkthrough
Two AWS CloudFormation stacks cover the setup that is identical in every deployment. The Snowflake and Lake Formation steps stay as explicit SQL and AWS CLI commands, so you can adapt them to your existing Snowflake account and VPC.
| Step | What you configure | How you run it |
| 1 & 2 | Cognito user pool, machine-to-machine app client, and the Lambda function that adds the aud claim |
Launch Stack, snowflake-federation-oauth |
| 3 | Snowflake security integration, read-only role, service user, and table grants | Snowflake SQL worksheet |
| 4 | PrivateLink authorization for your AWS account | AWS CLI and Snowflake SQL worksheet |
| 5 | VPC, PrivateLink endpoint, Route 53 private hosted zone, and the Lake Formation data access role | Launch Stack, snowflake-federation-network |
| 6 | S3 location registration, AWS Glue connection, federated catalog, and Lake Formation permissions | AWS CLI |
| 7 | Query validation | Athena console |
Step 1: Deploy the Cognito user pool and token customization Lambda function
Snowflake External OAuth validation requires an aud claim in each access token. The OAuth2 client_credentials grant doesn’t define that claim, so the Pre Token Generation trigger adds it. This stack creates the user pool, the machine-to-machine app client, and a Pre Token Generation Lambda function that adds the claim. The stack also writes the app client secret to AWS Secrets Manager in the format the AWS Glue connection expects. It then generates the Snowflake SQL statements you run in Step 3.
- Choose Launch Stack.

- In the Region selector, confirm the Region matches your Snowflake account Region, then choose Next.
- For Stack name, keep
snowflake-federation-oauth. Leave all parameters at their default values, then choose Next. - On Configure stack options, keep the defaults and choose Next.
- On Review and create, select I acknowledge that AWS CloudFormation might create IAM resources with custom names, then choose Submit.
- When the stack status is
CREATE_COMPLETE, choose the Outputs tab.
You use six of the outputs in later steps.
| Output | Used in |
VerifyAudClaimCommand |
Step 2 |
SnowflakeSecurityIntegrationSQL |
Step 3 |
OAuthClientSecretArn |
Step 5 and Step 6 |
CognitoTokenEndpoint, CognitoClientId and CognitoScope |
Step 3 and Step 6 |
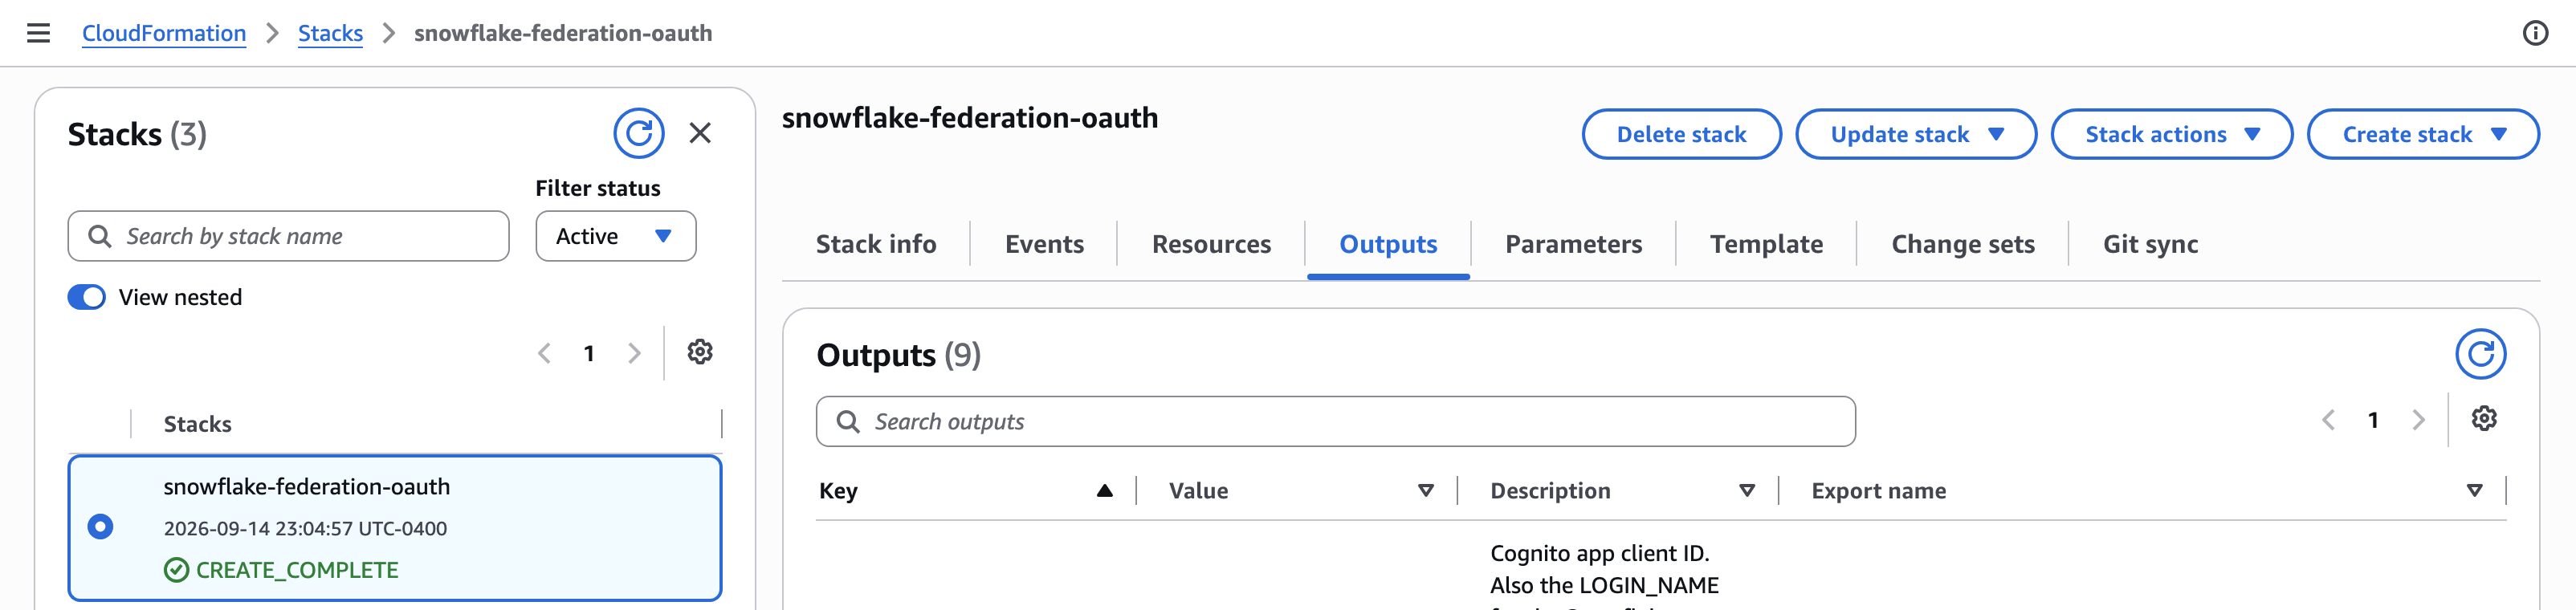
Figure 2: CloudFormation Outputs tab showing the values used in later steps
Note: After the connection validates in Step 6, AWS Glue caches the token it mints by writing it back into this secret. Treat read access to the secret as read access to the federated tables.
Step 2: Verify the access token
Confirm that the Lambda function is adding the claim before you configure Snowflake. A missing claim doesn’t fail here. It surfaces several steps later as an AWS Glue connection that can’t authenticate, which is harder to attribute.
- On the Outputs tab, copy the value of
VerifyAudClaimCommand. - Choose the AWS CloudShell icon on the console navigation bar, as shown in the following screenshot.
- Paste the command and run it. Confirm two values in the output. The
audclaim matches your Cognito client ID, andscopeissnowflake/catalog.read.
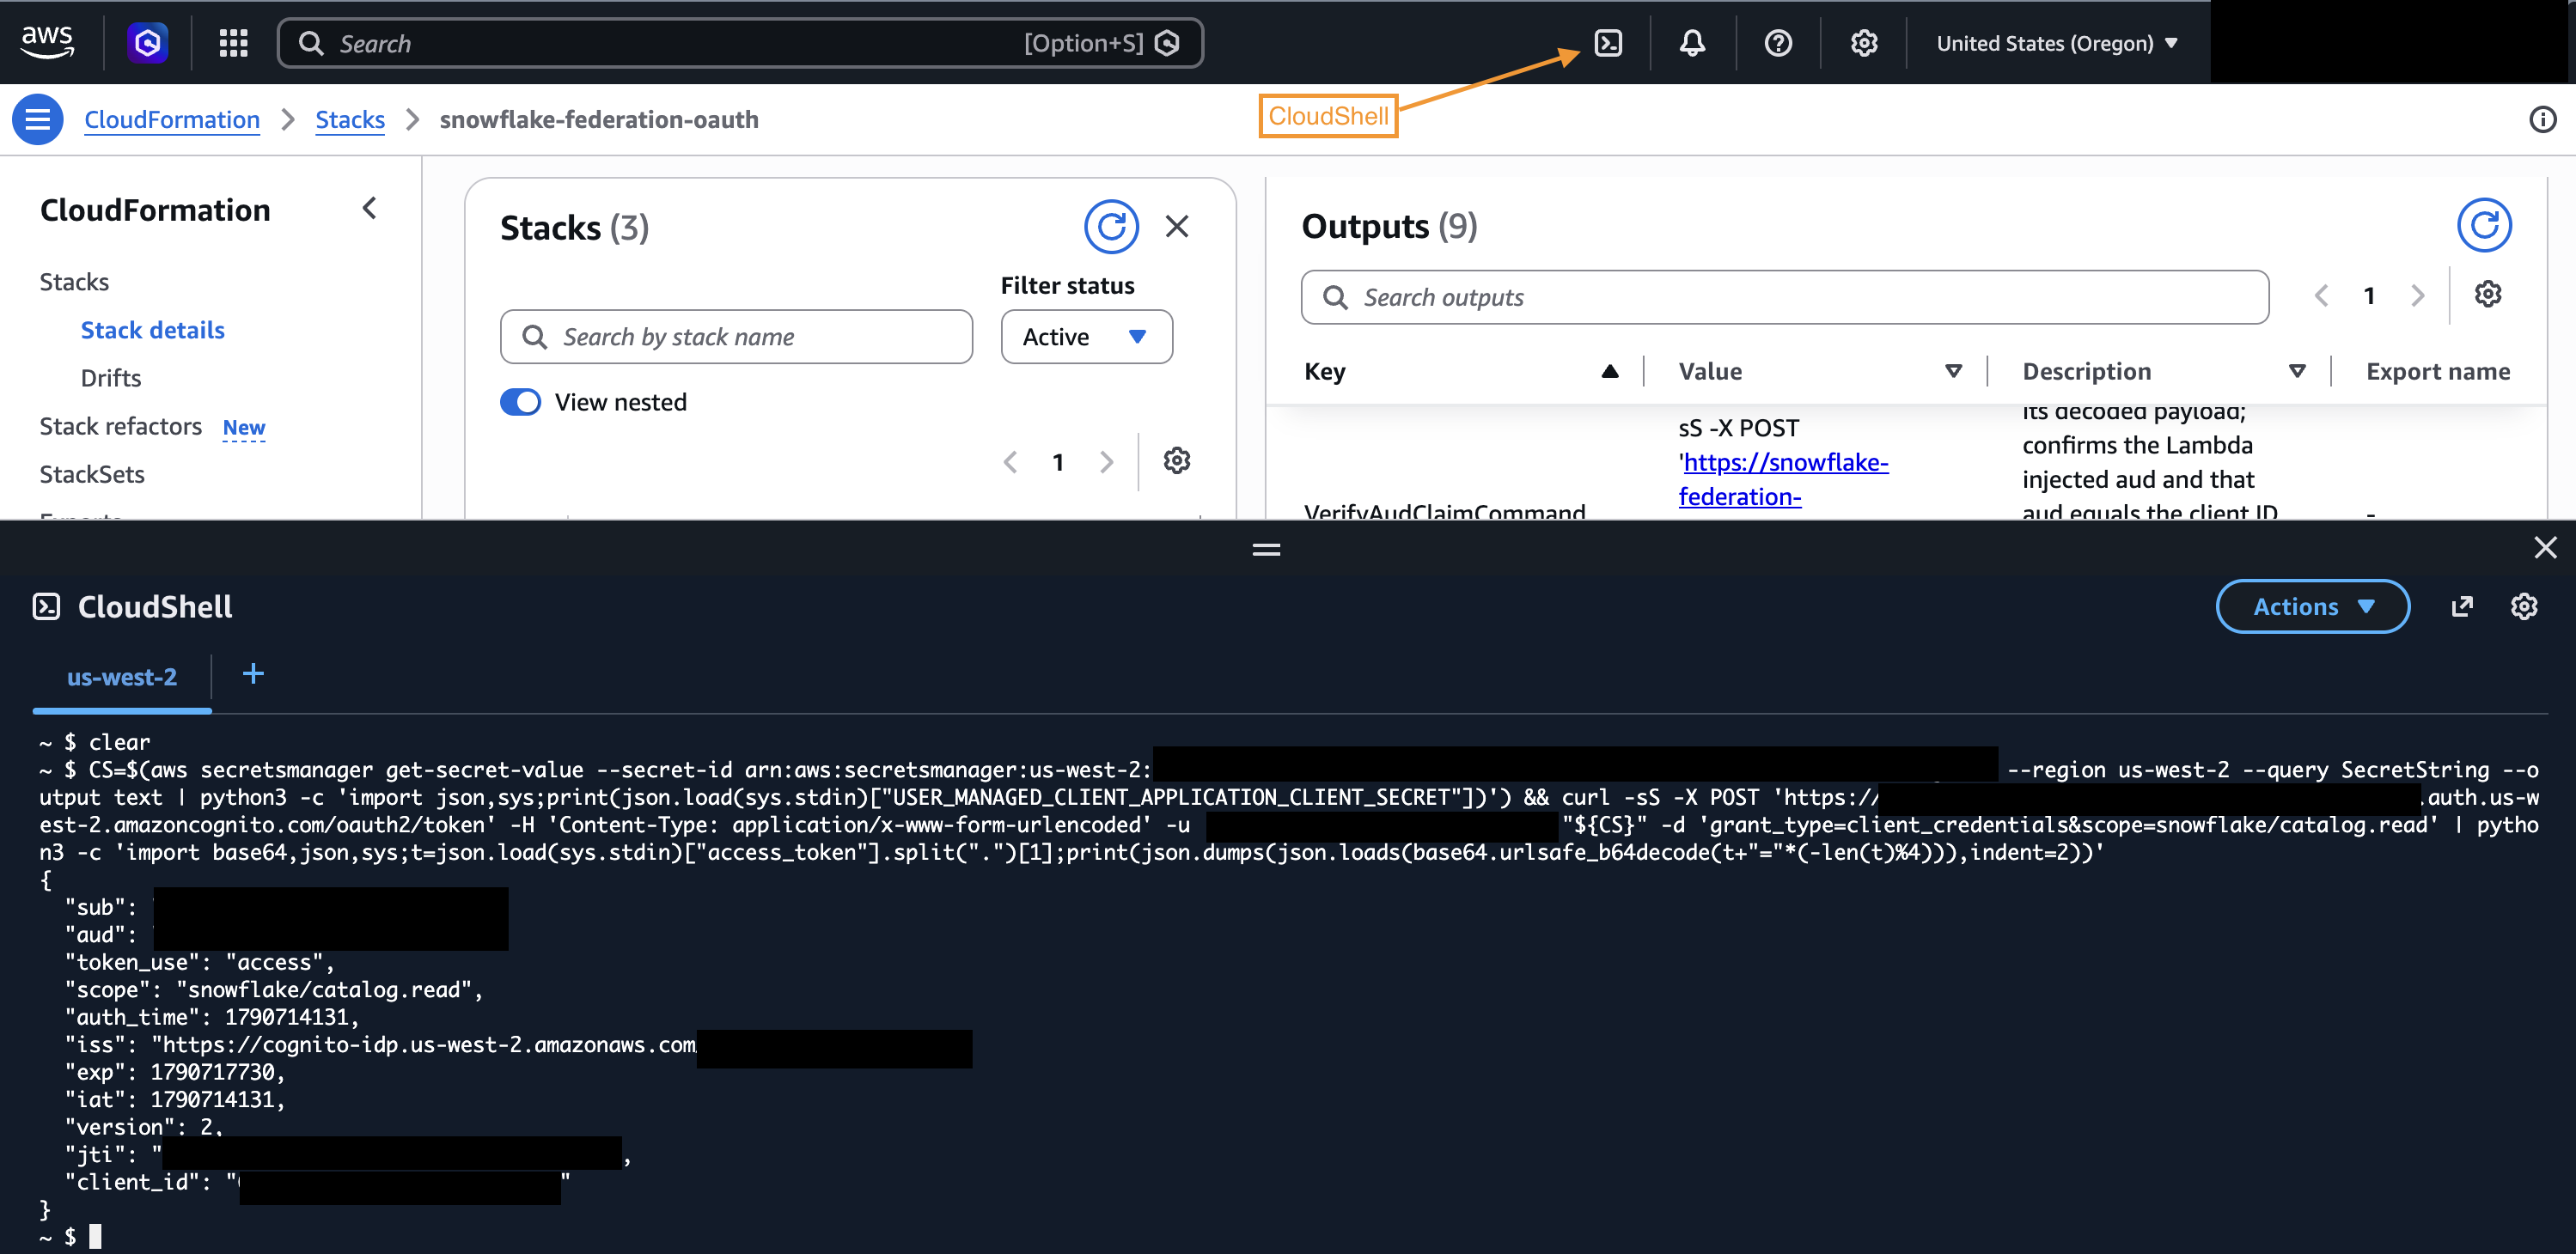
Figure 3: Decoded access token payload showing the injected aud claim and the catalog.read scope
Step 3: Configure Snowflake
In this step you configure Snowflake to trust Cognito tokens, create the service user that Lake Formation authenticates as, and grant it read access to your tables.
- Run the following statement in a Snowflake worksheet, replacing the three placeholders with the
CognitoIssuerUri,CognitoJwksUrl, andCognitoClientIdoutputs from Step 1. TheSnowflakeSecurityIntegrationSQLoutput contains the same statement with your values filled in. CREATE omits OR REPLACE, so it fails rather than overwriting an existing integration.
Snowflake normally takes the role from a session:role:<ROLE> scope, which Amazon Cognito custom scopes can’t carry because they use the form resourceServer/scope. The statement therefore sets EXTERNAL_OAUTH_ANY_ROLE_MODE to ENABLE, which lets the session use any role granted to the service user, so keep that user to a single role. The blocked roles list also covers SYSADMIN and USERADMIN, which the Snowflake default list doesn’t.
- Create the read-only role and the service user. Set LOGIN_NAME to the
CognitoClientIdoutput, because the token’ssubclaim carries the client ID and the integration mapssubtologin_name.
- Grant the role read access to the tables you want to federate. For the privileges the Iceberg REST Catalog API requires, see Configure access control in the Snowflake documentation.
Note: Federate a schema that contains only Snowflake-managed Iceberg tables. An externally managed table can fail the entire table listing. Converted tables, tables loaded from Iceberg-compatible Parquet files and clones whose source table the role can’t access aren’t supported. Tables with mixed-case quoted names aren’t federated, because the connection you create in Step 6 sets CATALOG_CASING_FILTER to UPPERCASE_ONLY.
Snowflake masking and row access policies don’t apply when Athena reads a federated table, because Lake Formation vends the Amazon S3 credentials and Athena reads the Parquet files directly. Keep tables that rely on them out of the federated schema or recreate the controls in Lake Formation and test them.
- Next, find the Amazon S3 bucket and prefix your external volume writes to. You need both in Step 5.
STORAGE_BASE_URL holds the bucket and an optional prefix. For s3://my-bucket/iceberg/, the bucket is my-bucket and the prefix is iceberg. If nothing follows the bucket name, leave the prefix blank in Step 5. A prefix is better, because it limits the data access role to that path. If ENCRYPTION_TYPE is AWS_SSE_KMS, note the key in ENCRYPTION_KMS_KEY_ID for Step 5. If it is NONE, check the bucket’s default encryption in the Amazon S3 console. The Snowflake role that owns the Iceberg tables must keep the USAGE privilege on the external volume, or operations that request vended credentials fail.
If the bucket uses a customer managed KMS key, set KMS_KEY_ID on the external volume to the full key ARN. Then add the following statement to the key policy, so the session Snowflake uses for the role in STORAGE_AWS_ROLE_ARN can read the encrypted files. Without it, the AWS Glue connection fails with an error that says no session policy allows kms:Decrypt.
Step 4: Authorize AWS PrivateLink in Snowflake
Snowflake requires proof that you own the AWS account before it accepts a PrivateLink connection. You provide that proof as an AWS Security Token Service (AWS STS) federation token. You must call get-federation-token with the long-term credentials of an IAM user, because AWS STS doesn’t support calling it with temporary credentials from an assumed role.
- Using an IAM user with long-term access keys, generate a federation token:
The token appears in the SQL statement, so Snowflake keeps it in query history. The 15-minute duration limits how long it stays valid.
- In your Snowflake worksheet, pass your AWS account ID and the full JSON output from the previous command:
The output confirms that Snowflake authorized PrivateLink for your account.
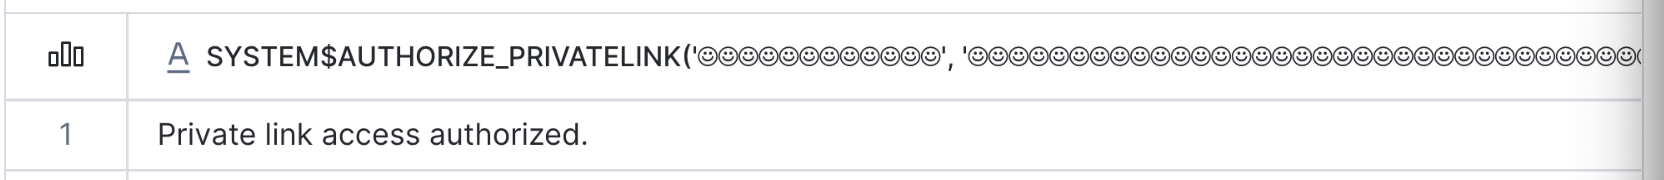
Figure 4: Snowflake output confirming PrivateLink authorization
- Retrieve the two values you need for the stack in Step 5:
Record both values. privatelink_hostname is the Snowflake PrivateLink hostname, and vpce_service_name is the endpoint service name.
After authorization succeeds, delete the temporary IAM user and its access key. Revoking PrivateLink access later requires a new federation token, so recreate a similar user at that point. For more information, see How to retrieve a Federation Token from AWS for PrivateLink Self-Service.
Step 5: Set up VPC and PrivateLink connectivity
This stack creates the interface VPC endpoint to the Snowflake PrivateLink service and the Amazon Route 53 private hosted zone that resolves your Snowflake hostname to it. It also creates the security group that the endpoint shares with the AWS Glue connection. Keep Existing VPC ID blank and it also builds a VPC with public and private subnets and a NAT gateway.
To use an existing VPC, supply Existing VPC ID and two or more private subnet IDs in different Availability Zones. The stack then creates no subnets and no NAT gateway, so confirm three things first:
- You have enabled DNS resolution and DNS hostnames on the VPC.
- The private subnets have a
0.0.0.0/0route to a NAT gateway, which the AWS Glue connection uses to reach the Amazon Cognito token endpoint. Amazon Cognito doesn’t support AWS PrivateLink, but the traffic stays on the AWS network because both sit in the same Region. Without this route, the stack still succeeds and the connection fails in Step 6. - No Amazon Route 53 private hosted zone for
privatelink.snowflakecomputing.comis already associated with the VPC. A second zone for the same domain makes name resolution unpredictable.
To deploy the stack, complete the following steps:
- Choose Launch Stack.
- Confirm the Region selector matches your Snowflake account Region, then choose Next.
- For Stack name, keep
snowflake-federation-network, then enter the following parameters.
| Parameter | Value |
| Snowflake PrivateLink hostname | privatelink_hostname from Step 4 |
| Snowflake PrivateLink service name | vpce_service_name from Step 4 |
| Iceberg S3 bucket name | The bucket in the STORAGE_BASE_URL output from Step 3 |
| Iceberg data key prefix | The prefix in the STORAGE_BASE_URL output from Step 3. Leave blank if you have none |
| Iceberg bucket KMS key ARN | KMS key ARN. Leave blank if the bucket does’t use KMS |
| OAuth client secret ARN | OAuthClientSecretArn from Step 1 |
If the bucket uses SSE-KMS, the stack grants the data access role kms:Decrypt on the key you enter. The default key policy already allows this. If your key policy doesn’t delegate access to IAM, add the role as a key user.
- Choose Next, keep the defaults on Configure stack options, and choose Next.
- On Review and create, select I acknowledge that AWS CloudFormation might create IAM resources with custom names, then choose Submit.
- When the stack status is
CREATE_COMPLETE, which takes about 5 minutes, choose the Outputs tab and recordPrivateSubnetIds,GlueConnectionSecurityGroupId,LakeFormationDataRoleArn, andRegisteredS3Location. You use all four values in Step 6.
NAT gateway and the interface VPC endpoint carry hourly and data processing charges. For more information, see Amazon VPC pricing.
Step 6: Register with Lake Formation and create the federated catalog
The remaining setup is a sequence of AWS CLI commands. Run them in AWS CloudShell in the same Region as both stacks.
- Set the values used by the commands that follow. Fill in the Region, and the stack outputs from Step 1 and Step 5.
- Register the Amazon S3 location that holds your Iceberg data. This is what lets Lake Formation vend scoped credentials to Athena for the underlying data files.
- Create the AWS Glue connection. This writes the definition to a file, then creates it.
- Check the connection status. AWS Glue validates asynchronously. It creates the network interface, completes the OAuth2 exchange with Amazon Cognito, and calls the Snowflake Iceberg REST API over AWS PrivateLink. Repeat this command until it returns
READY, which takes approximately 5–10 minutes.
If it returns FAILED, read the reason and correct the Snowflake configuration from Step 3. A missing security integration, service user, or grant is the usual cause.
Then delete the connection before you retry, because the name stays in use.
- Register the connection with Lake Formation using privileged access. A federated catalog can only use a connection registered this way.
- Create the federated catalog, then confirm the tables surface through it.
- Grant Lake Formation permissions to the data teams that will query the tables. The principal that created the catalog can already query it. Every other principal needs an explicit grant, including other Lake Formation administrators.
Note: The catalog ID for a federated catalog is :, not the bare account ID. Using the bare account ID grants permissions on the local AWS Glue Data Catalog instead, which succeeds and then leaves Athena returning an access denied error.
Step 7: Query the federated tables from Amazon Athena
- Open the Amazon Athena console and choose Query editor. If this is the first time you use Athena in this Region, choose Settings, then Manage, and set an Amazon S3 location for query results.
- In the left panel, select the following.
| Field | Value |
| Data source | AwsDataCatalog |
| Catalog | Your federated catalog, for example snowflake-federation-catalog |
| Database | Your Snowflake schema name, in lowercase |
- Run the following query:
Rows in the results pane confirm the federation works end to end, as shown in the following screenshot.
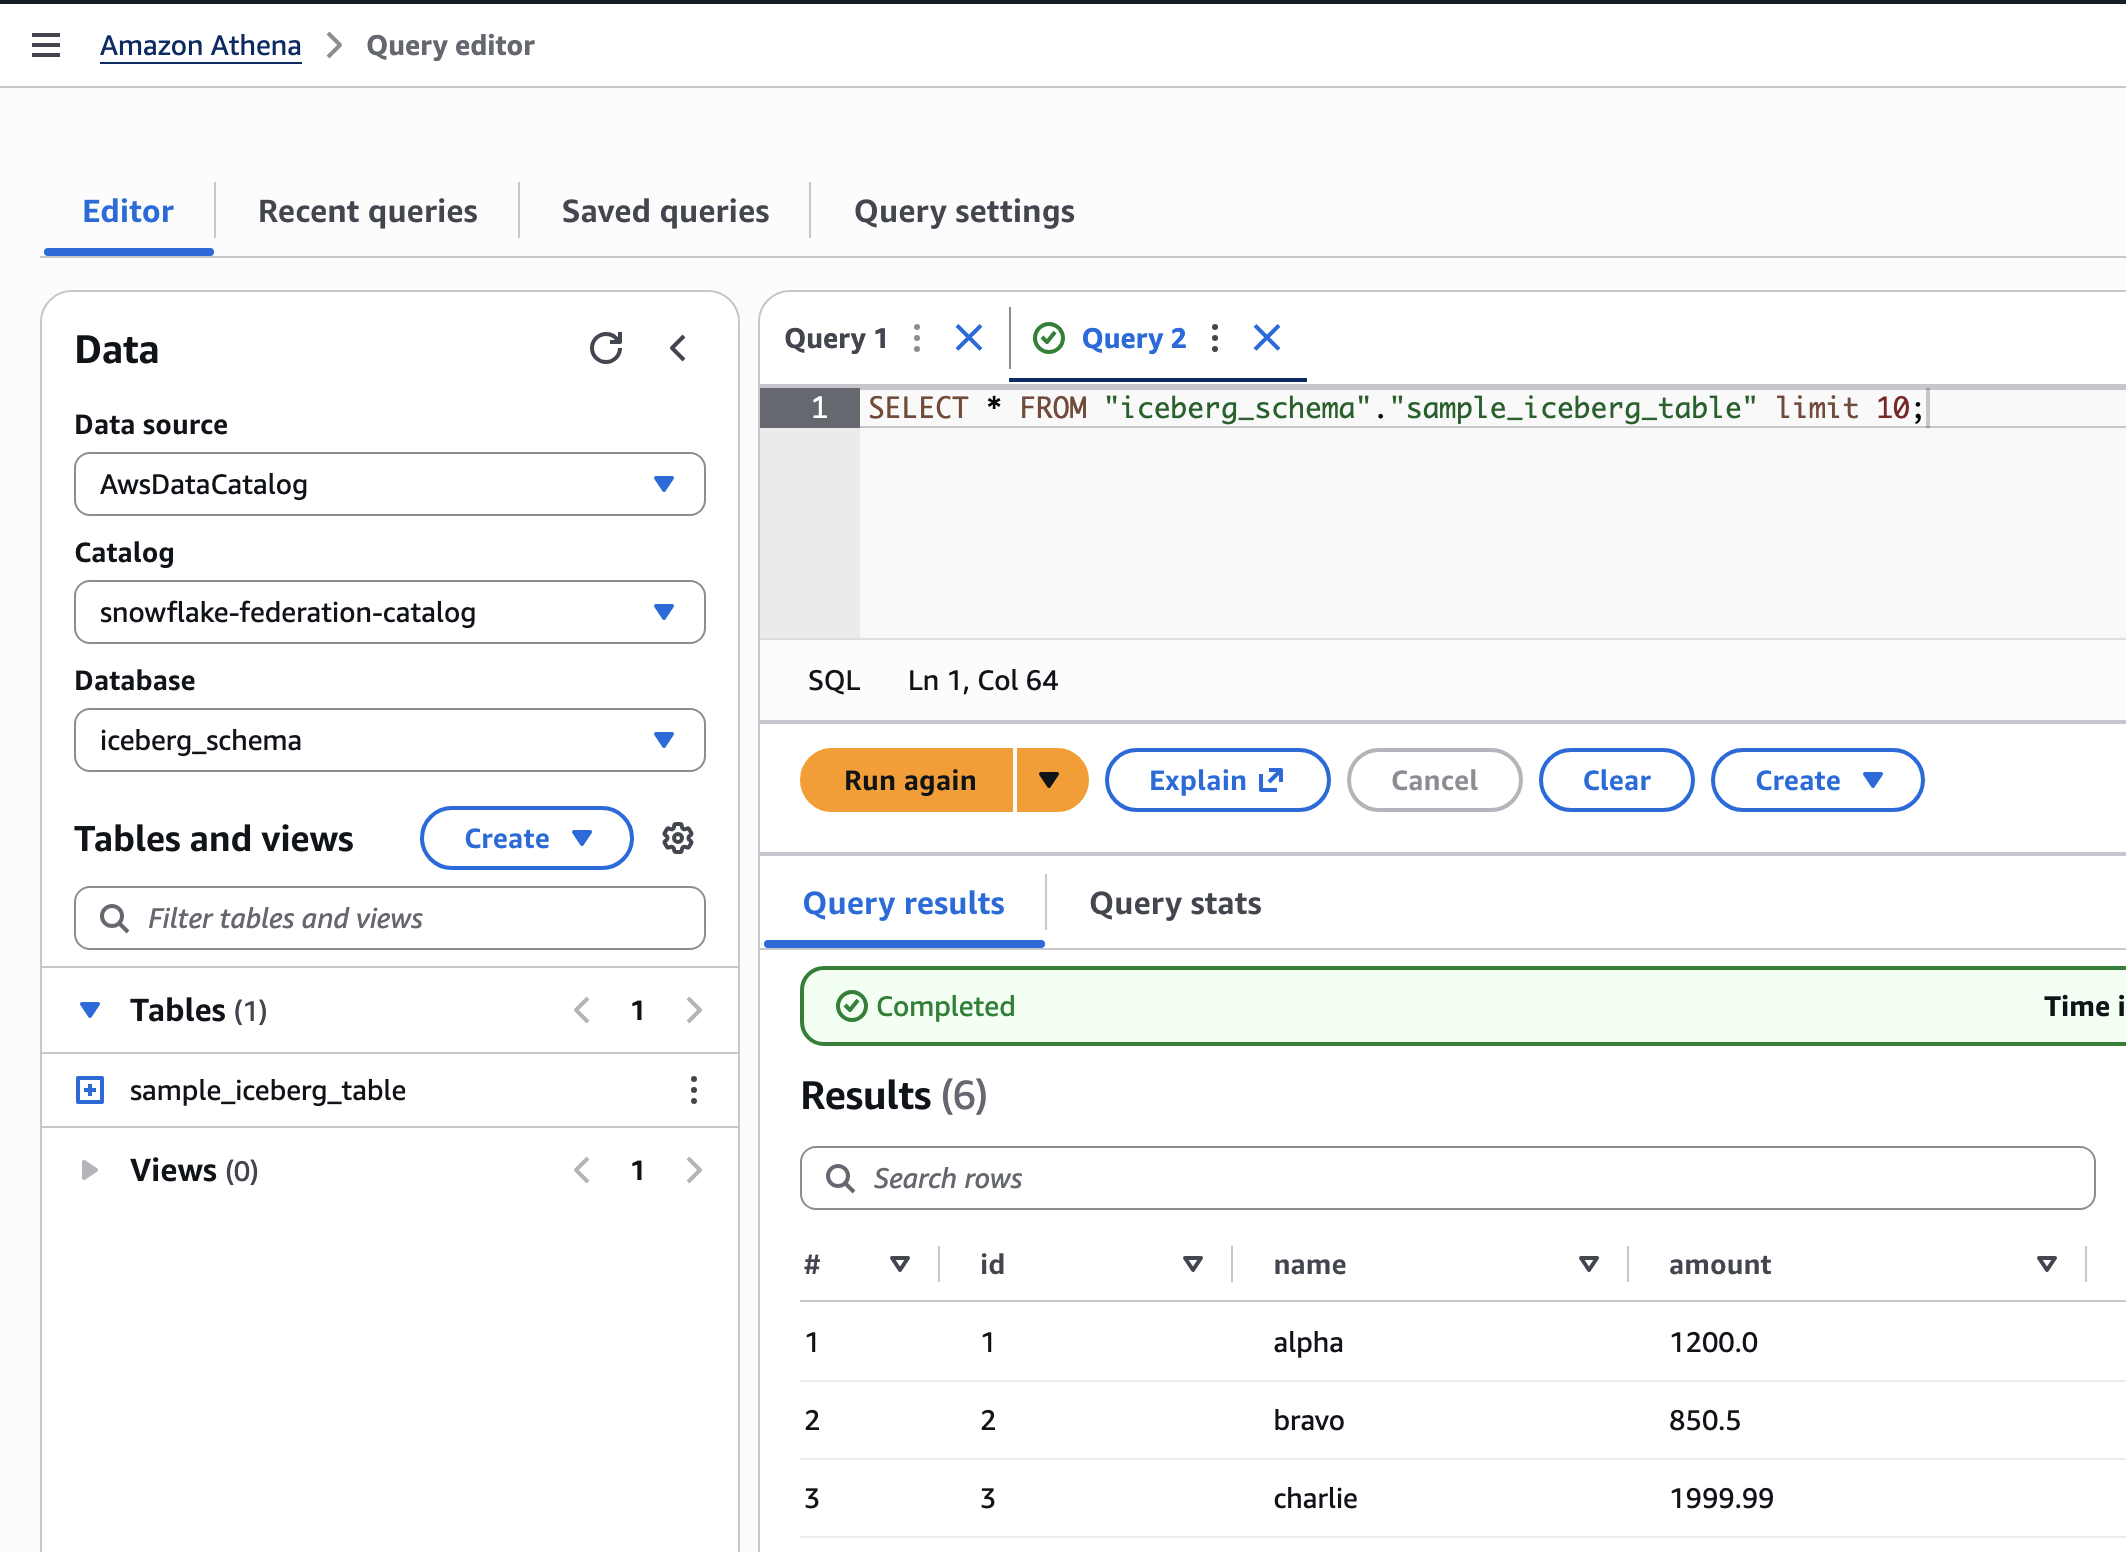
Figure 5: Query results in Amazon Athena from a Snowflake-managed Iceberg table
To confirm that Athena reads current Snowflake data rather than a copy, insert a row in Snowflake and run the query again. The new row appears with no additional data movement into your AWS account.
Dropping a table in Snowflake doesn’t revoke the Lake Formation permissions granted on it. Revoke those permissions explicitly when you remove a federated table.
Clean up
To avoid incurring future charges, delete the resources you created while following this post. Complete the following steps in both your AWS account and your Snowflake account.
AWS account
- On the AWS Lake Formation console, choose Catalogs, select your federated catalog, then choose Actions and Delete catalog.
- Record the network interfaces the AWS Glue connection created, while the connection still exists. Filtering on the Step 5 security group and the
ICEBERGRESTCATALOGdescription keeps the list to this deployment.
- Deregister and delete the AWS Glue connection. Do this before you delete the stacks, because the stack deletion fails while the connection’s network interfaces still hold the security group. Run the following in AWS CloudShell, replacing the Region, account ID, and connection name with your values.
- Deleting the connection releases its network interfaces, but they stay in the in-use state for several minutes and AWS Glue doesn’t remove them. Wait for each one to reach available, because the Amazon Elastic Compute Cloud (Amazon EC2) console Detach action fails even with Force detachment selected. The following script checks each interface you recorded and deletes it when ready.
- On the Lake Formation console, under Administration, choose Data lake locations, select the registered Amazon S3 location, then choose Actions and Remove.
- On the AWS CloudFormation console, delete
snowflake-federation-networkfirst, thensnowflake-federation-oauth. This removes the VPC endpoint, the Amazon Route 53 private hosted zone, the security group, and the IAM role. It also removes the Amazon Cognito user pool, the AWS Lambda function, and the client secret. If the stack created the VPC, subnets, and NAT gateway, it removes those too.
Snowflake account
- Open a SQL worksheet and run the following:
- Revoke the PrivateLink authorization for your AWS account. This requires a fresh federation token, generated the same way as during setup, from an IAM user with long-term access keys:
- Confirm the account is no longer authorized:
Deleting the federated catalog and connection doesn’t delete data in Snowflake or Amazon S3. It only removes the federation configuration in your AWS account.
Conclusion
In this post, you learned how to federate Snowflake Horizon Catalog Iceberg tables into AWS Lake Formation and query them from Amazon Athena. Amazon Cognito handled the OAuth2 tokens for machine-to-machine authentication. To extend this pattern to additional workloads, create a new app client in your Cognito user pool and a corresponding read-only Snowflake role.
To get started, see Catalog federation to remote Iceberg catalogs and Federate to Snowflake Iceberg Catalog in the AWS Lake Formation Developer Guide, and External OAuth overview in the Snowflake documentation. If you have feedback about this post, submit comments in the Comments section.
About the authors
Allocate shared Amazon MSK costs to Kafka topics for cost visibility
Post Syndicated from Durai Krishnan original https://aws.amazon.com/blogs/big-data/allocate-shared-amazon-msk-costs-to-kafka-topics-for-cost-visibility/
Your AWS bill shows Amazon Managed Streaming for Apache Kafka (Amazon MSK) charges at the cluster level, with one cost line item for each cluster. If your organization runs one cluster for several teams, and each team owns its own Kafka topics, you need a way to show each team its share of the spend. This post shows how you can produce that per-topic cost view by combining cluster-level billing data with per-topic usage metrics. The result gives each team a usage-based picture of what it consumes.
Bringing cost and usage together
You can use Amazon MSK to run Apache Kafka at scale while AWS manages the underlying infrastructure, so you can focus on configuring and operating your applications. Many organizations consolidate multiple workloads onto a single cluster, where each team or application owns a set of Kafka topics. Consolidation can help you improve operational efficiency. When you implement per-topic cost visibility, you can show each team its share of the cluster spend.
Producing that view draws on two sources of data, and the solution brings them together.
Cost: cluster-level billing in the CUR
You can locate MSK charges in your AWS Cost and Usage Report (CUR) by cluster ARN and see operations such as RunBroker, RunVolume, and Bandwidth. You use this cluster-level cost as the starting point when you allocate costs to your topics.
Usage: per-topic metrics without cost context
Amazon MSK surfaces per-topic throughput metrics, which provide the usage signal you use to distribute cluster cost across topics. You can use the cluster name that Amazon MSK provides with these metrics. Map that name to the cluster ARN to join usage with billing and produce per-topic cost.
Solution overview
Option A – Enhanced Monitoring: Uses per-topic Amazon CloudWatch metrics published by Amazon MSK.
Option B – Open Monitoring with Amazon Managed Service for Prometheus: A cost-optimized alternative. This option uses the MSK Open Monitoring endpoint at no additional charge and keeps metric cost growth low as topic count grows.
Both options use the same allocation logic and output. Switch between them with one configuration value.
The pipeline runs in five steps:
- Read cluster cost from CUR – A daily AWS Lambda function reads MSK line items by cluster ARN and day.
- Bridge identifiers – The function calls
ListClustersV2to map cluster name to ARN. - Read per-topic usage – The function retrieves each topic’s daily throughput. This step differs between Option A and Option B.
- Allocate proportionally – For each day, the function distributes that day’s cluster cost across topics based on each topic’s share of throughput.
- Publish results – The function writes allocation data as Apache Parquet to Amazon Simple Storage Service (Amazon S3) and refreshes an Amazon Athena table. You visualize the results in AWS Quick Sight.
The following diagram shows the pipeline.
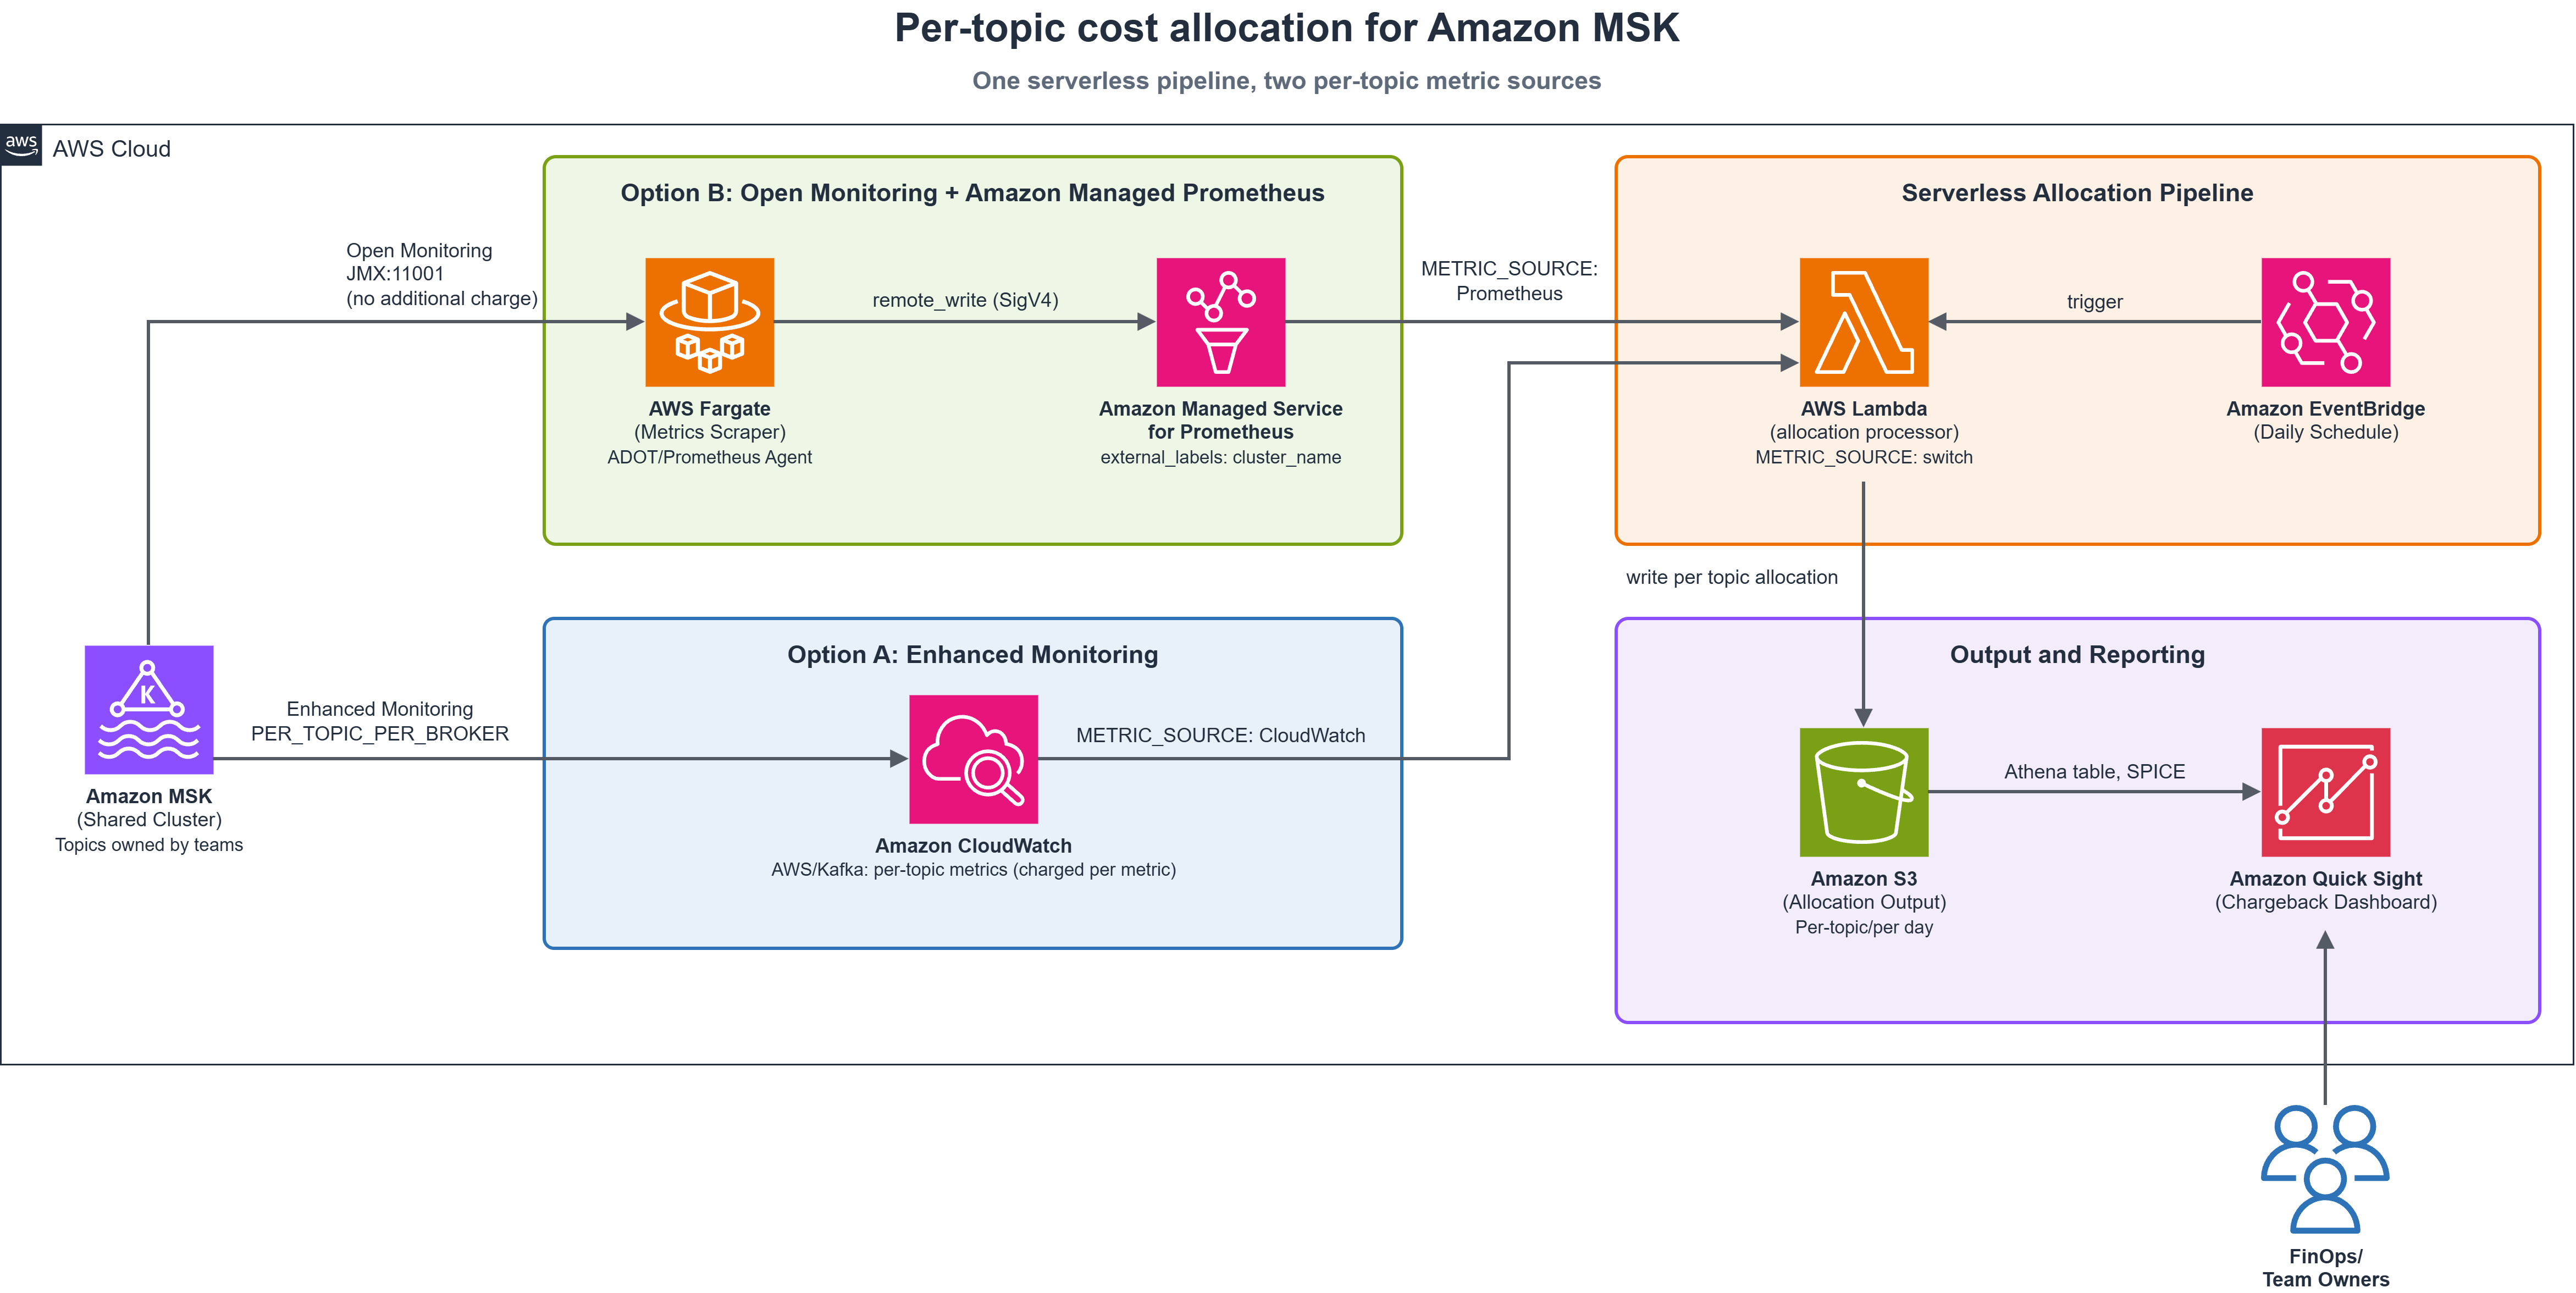
Figure 1: Solution architecture. A single serverless pipeline supports both per-topic metric sources, selected with the METRIC_SOURCE environment variable
How the allocation works
For each cluster and day, the function computes each topic’s share of ingress bytes and applies that share to the cost:
The function assigns 30 percent of the cost to a topic that carries 30 percent of ingress. Allocations always sum to the day’s total. During a partial outage, the function distributes costs only among topics for which you have configured metrics.
Two behaviors to know:
- Idle topics get no row. If only 3 of 20 report traffic, those 3 absorb the full cost. The
allocation_methodcolumn catches this. - If no topic reports traffic for a cluster-day, the function falls back to an even split across all topics you have configured.
Why bytes-in as the allocation weight
Bytes-in is available from both metric sources and correlates well with broker compute and network cost.
However, bytes-in is a proxy. Its limitations:
- It can’t see retention. Two topics with identical throughput but different retention periods use different storage.
- It can’t see replication factor or compression, which change actual bytes on disk.
- It can’t see consumer fan-out. A topic read by ten consumer groups looks the same as one read by one.
Other factors can drive your costs, such as egress (consumer read volume), partition count, or storage retention. In that case, you can adapt the same pipeline to use a different allocation weight or a blended model.
Report unallocated charges (data transfer, tiered storage, MSK Connect) explicitly so finance has a more complete picture.
Prerequisites
Before you begin, make sure you have:
- An active Amazon MSK Provisioned cluster with topics carrying traffic. (Amazon MSK Serverless is out of scope. It bills differently and does not expose per-topic
BytesInPerSec.) - AWS CUR (or AWS Data Exports for CUR 2.0) delivering Parquet to Amazon S3 with resource IDs enabled. Uses CUR 2.0 snake_case column names.
- An AWS Glue catalog table over the CUR data with correct partition configuration.
- Permissions to create AWS Lambda functions, IAM roles, Athena tables, and Quick Sight resources.
- Quick Sight Enterprise edition (for SPICE datasets and row-level security in the reporting layer).
- For Option B only: a private subnet in the MSK virtual private cloud (VPC) for the scraper, and an Amazon Managed Service for Prometheus workspace.
Timing: CUR lags up to 24 hours. Per-topic metrics exist only from the moment you enable them.
Sourcing per-topic usage: Two options
How you collect per-topic usage is the main design decision in this solution, because it determines your monitoring cost and setup effort. The pipeline supports both options, and you select one with the METRIC_SOURCE environment variable.
Option A (recommended starting point): Enhanced Monitoring
When you set Enhanced Monitoring to PER_TOPIC_PER_BROKER, MSK publishes per-topic throughput metrics to CloudWatch. The Lambda function aggregates each topic’s daily usage with GetMetricStatistics calls.
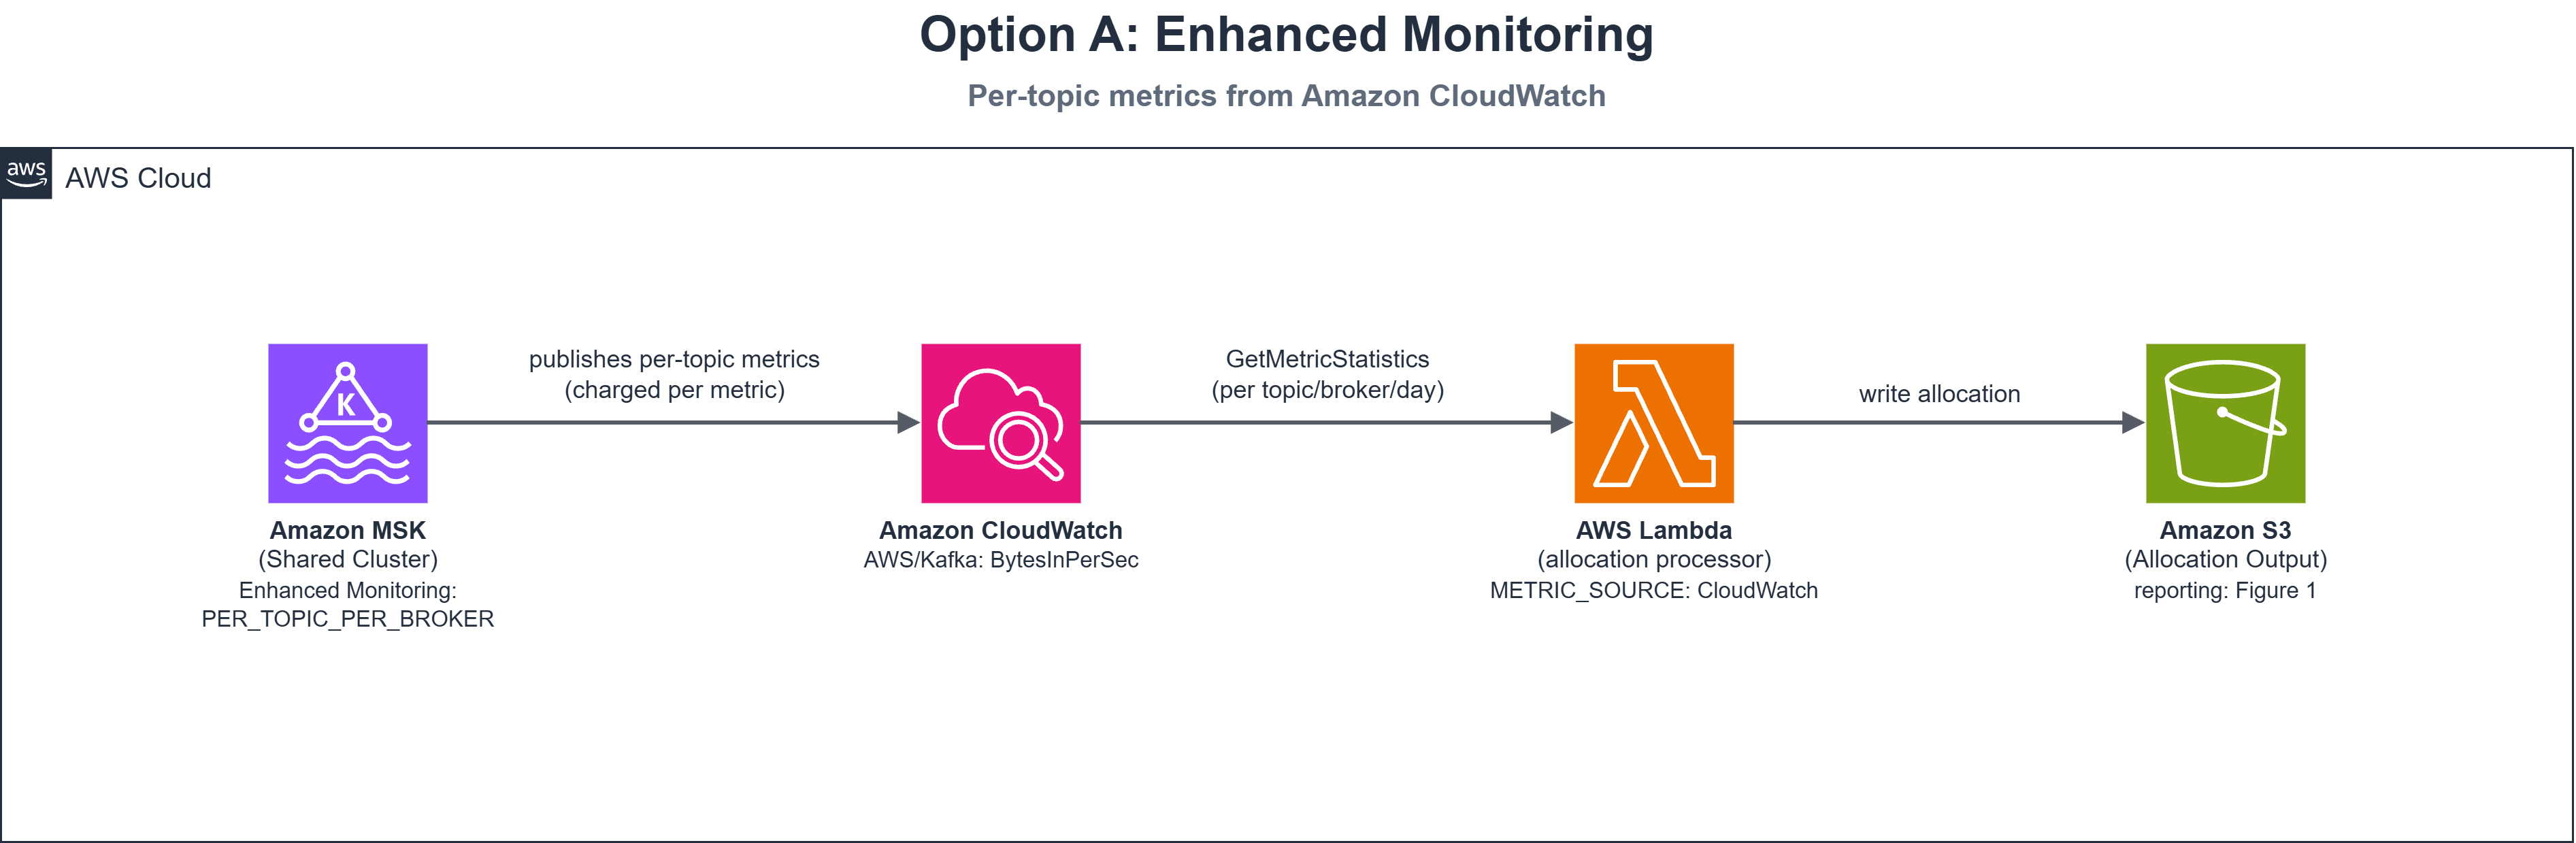
Figure 2: Option A collection path. Amazon MSK publishes per-topic metrics to CloudWatch, and the allocation function reads them directly
Code sample — reading per-topic metrics from CloudWatch:
Note: BytesInPerSec is a rate. Period=86400 with Statistics=[Sum] returns a valid relative weight for proportional allocation, not total bytes.
Why start here: Nothing to deploy. Change one cluster setting and metrics appear in CloudWatch.
The trade-off: CloudWatch bills per metric. PER_TOPIC_PER_BROKER publishes a metric set for every topic-broker pair, so cost grows with both.
Scaling tip: At scale (over 50 clusters, over 200 topics), switch to GetMetricData (up to 500 metrics per call) instead of iterating GetMetricStatistics.
Option B (cost-optimized): Open Monitoring with Amazon Managed Service for Prometheus
Kafka brokers expose operational metrics through Java Management Extensions (JMX). Amazon MSK Open Monitoring makes these infrastructure metrics available in Prometheus format on port 11001 at no cost.
You run a scraper (AWS Fargate with an AWS Distro for OpenTelemetry (ADOT) Collector) that forwards metrics to a Prometheus workspace through SigV4 remote write. The task role needs the aps:RemoteWrite permission.
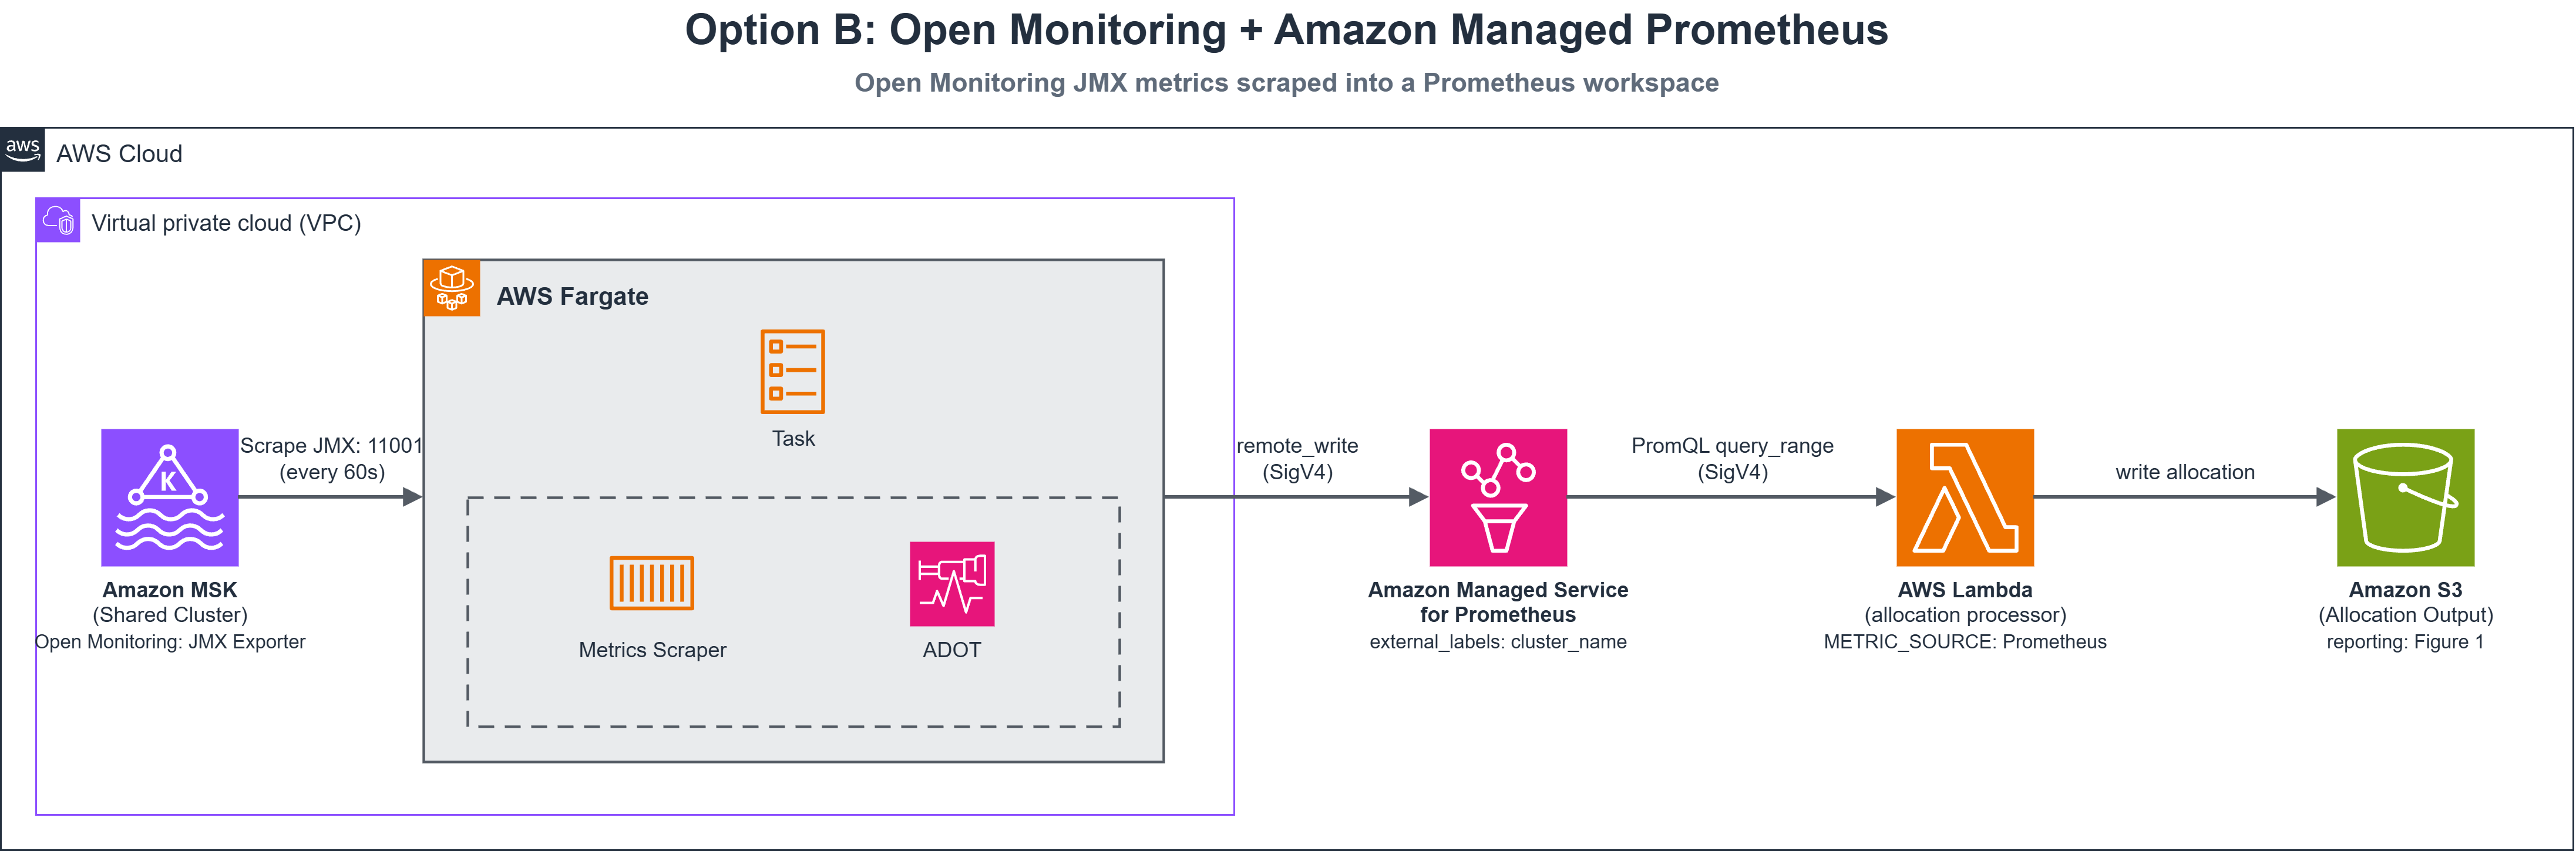
Figure 3: Option B collection path. A VPC scraper collects JMX metrics at no additional charge and forwards them to Prometheus
Scraper configuration (Prometheus agent):
Get broker hostnames from GetBootstrapBrokers. For dynamic lists, use Prometheus file_sd_configs.
PromQL query for per-topic usage:
This averages broker rates over 24 hours into one value per topic, producing a comparable weight.
Open Monitoring is available at no additional charge and the Prometheus workspace bills on samples ingested, so metric cost grows slowly. This suits large fleets.
How the function discovers topics
The function resolves topic lists through a tiered lookup:
- Static topic map – An environment variable holding JSON keyed by cluster name. No API calls needed. Works well when you already track topic ownership in config or infrastructure code.
- Amazon MSK ListTopics API – Control-plane call, no VPC connectivity needed.
- CloudWatch ListMetrics – Reads topics from metric dimensions (Enhanced Monitoring only).
- Previous allocation output – Falls back to yesterday’s topic list from S3.
The tiered lookup keeps the function working whether or not Enhanced Monitoring is enabled:
Choosing between the options
For steady topics, both options typically produce comparable results. The choice is cost and operating model:
| Option A: Enhanced Monitoring | Option B: Open Monitoring + Prometheus | |
| Per-topic metric cost | ~$90/cluster/month | None (Open Monitoring is at no additional charge) |
| Additional infra cost | None | ~$11/cluster/month (scraper + workspace) |
| Setup effort | Change one cluster setting | Deploy scraper, workspace, and VPC networking |
| Ongoing operations | None | Maintain one scraper per VPC |
| Scaling behavior | Grows with topics × brokers | Grows slowly from a much lower base |
| Time to first allocation | Next day | Next day (after a few days of setup) |
Note: Figures are illustrative, not AWS list prices. Recalculate using the CloudWatch, Prometheus, and Fargate pricing pages.
Guideline: if monitoring cost is below 5 percent of MSK spend, take Option A. Above 10 percent, Option B repays the setup quickly.
You can enable Enhanced Monitoring only on clusters where chargeback accuracy matters, and switch to Option B later with one environment variable change.
Deploying the allocation pipeline
Deploy with AWS Cloud Development Kit (AWS CDK). The core Lambda function (Python 3.11, 1 GB, 10-min timeout) uses the AWS SDK for pandas layer for Parquet processing. Two triggers invoke the function, for resilience:
- An Amazon S3 event notification fires when a new CUR Parquet file arrives, so allocation runs as soon as fresh cost data lands.
- An Amazon EventBridge rule runs daily at 06:00 UTC as a fallback, in case the S3 event doesn’t arrive or CUR delivery lags.
Set METRIC_SOURCE to cloudwatch for Option A or prometheus for Option B. For Option B, you also supply the workspace query endpoint and label names.
The handler at a glance
The following handler function orchestrates the five-step pipeline. Each step delegates to a dedicated function, described in the sections that follow.
CDK stack – Lambda function definition:
Triggers:
The stack provisions an Amazon Simple Queue Service (Amazon SQS) dead-letter queue with 14-day retention for failed invocations, Amazon Simple Notification Service (Amazon SNS) alerts, and CloudWatch alarms. To subscribe your team, add sns.Topic.add_subscription(subscriptions.EmailSubscription("[email protected]")) in CDK, or subscribe manually through the Amazon SNS console.
The stack creates the AWS Glue table over the allocation output, so you don’t need to write DDL by hand. Deploy it with:
Invoke the function once manually to produce a first allocation.
Reading CUR efficiently at scale
The function queries CUR through Amazon Athena to get only MSK rows. Filter on partition columns so Athena prunes whole partitions:
The query reads two months because AWS can update CUR line items after the first delivery. Adjust arn:aws:kafka: for GovCloud or the China Regions.
Publishing and querying the results
The function writes allocation results to Amazon S3 as Snappy-compressed Parquet, partitioned by billing period. Each row covers one topic on one day with cluster identity, usage weight, and allocated cost.
Each run overwrites the file for its billing period. This helps prevent double-counting on CUR redeliveries.
Output schema:
| Field | Description |
| account_id | AWS account that owns the cluster |
| cluster_name, cluster_arn | MSK cluster identity and join key back to the CUR |
| topic_name | Kafka topic |
| client_id | Owning team or client (from a configurable mapping) |
| allocation_date, year, month | The day this row covers, plus year and month for convenient filtering |
| bytes_in | Topic ingress used as the allocation weight |
| run_cost, storage_cost, total_cost | Allocated cost components |
| **cluster_*_cost_day** | Cluster totals for that day (for reconciliation against the bill) |
| allocation_method | “proportional” or “equal_split” – explains anomalies without re-running |
| generated_at | Timestamp of the run that produced this row |
Verifying the numbers
Run this reconciliation query before publishing a dashboard. Schedule it as a Lambda post-step with an AllocationVariance CloudWatch alarm:
An empty result means allocations reconcile. Rows indicate days where topic discovery and cost data disagreed.
Mapping topics to teams
The function derives owners from topic naming conventions. Pass an explicit topic-to-team map where conventions fail. Unmapped topics appear as unfamiliar owners.
Visualizing cost by topic in Quick Sight
Create an Athena data source in Quick Sight, import into SPICE, and schedule daily refreshes.
A useful dashboard typically includes:
- A detail table of cost by team, topic, and month.
- A bar chart of total cost by topic.
- Filter controls for cluster, topic, and time period.
Apply Quick Sight row-level security against client_id so teams see only their own numbers. Row-level security requires Enterprise edition.
Extending to multiple accounts
The pipeline extends to multi-account setups:
- The central account reads the consolidated CUR.
- The Lambda function assumes a read-only role in each member account (by using AWS Security Token Service (AWS STS)) to list clusters and read usage, writing one consolidated dataset.
- For Option B, a single central Prometheus workspace receives remote-writes from every member account’s scraper, each stamping its own
cluster_namelabel.
One dataset and one dashboard across all accounts.
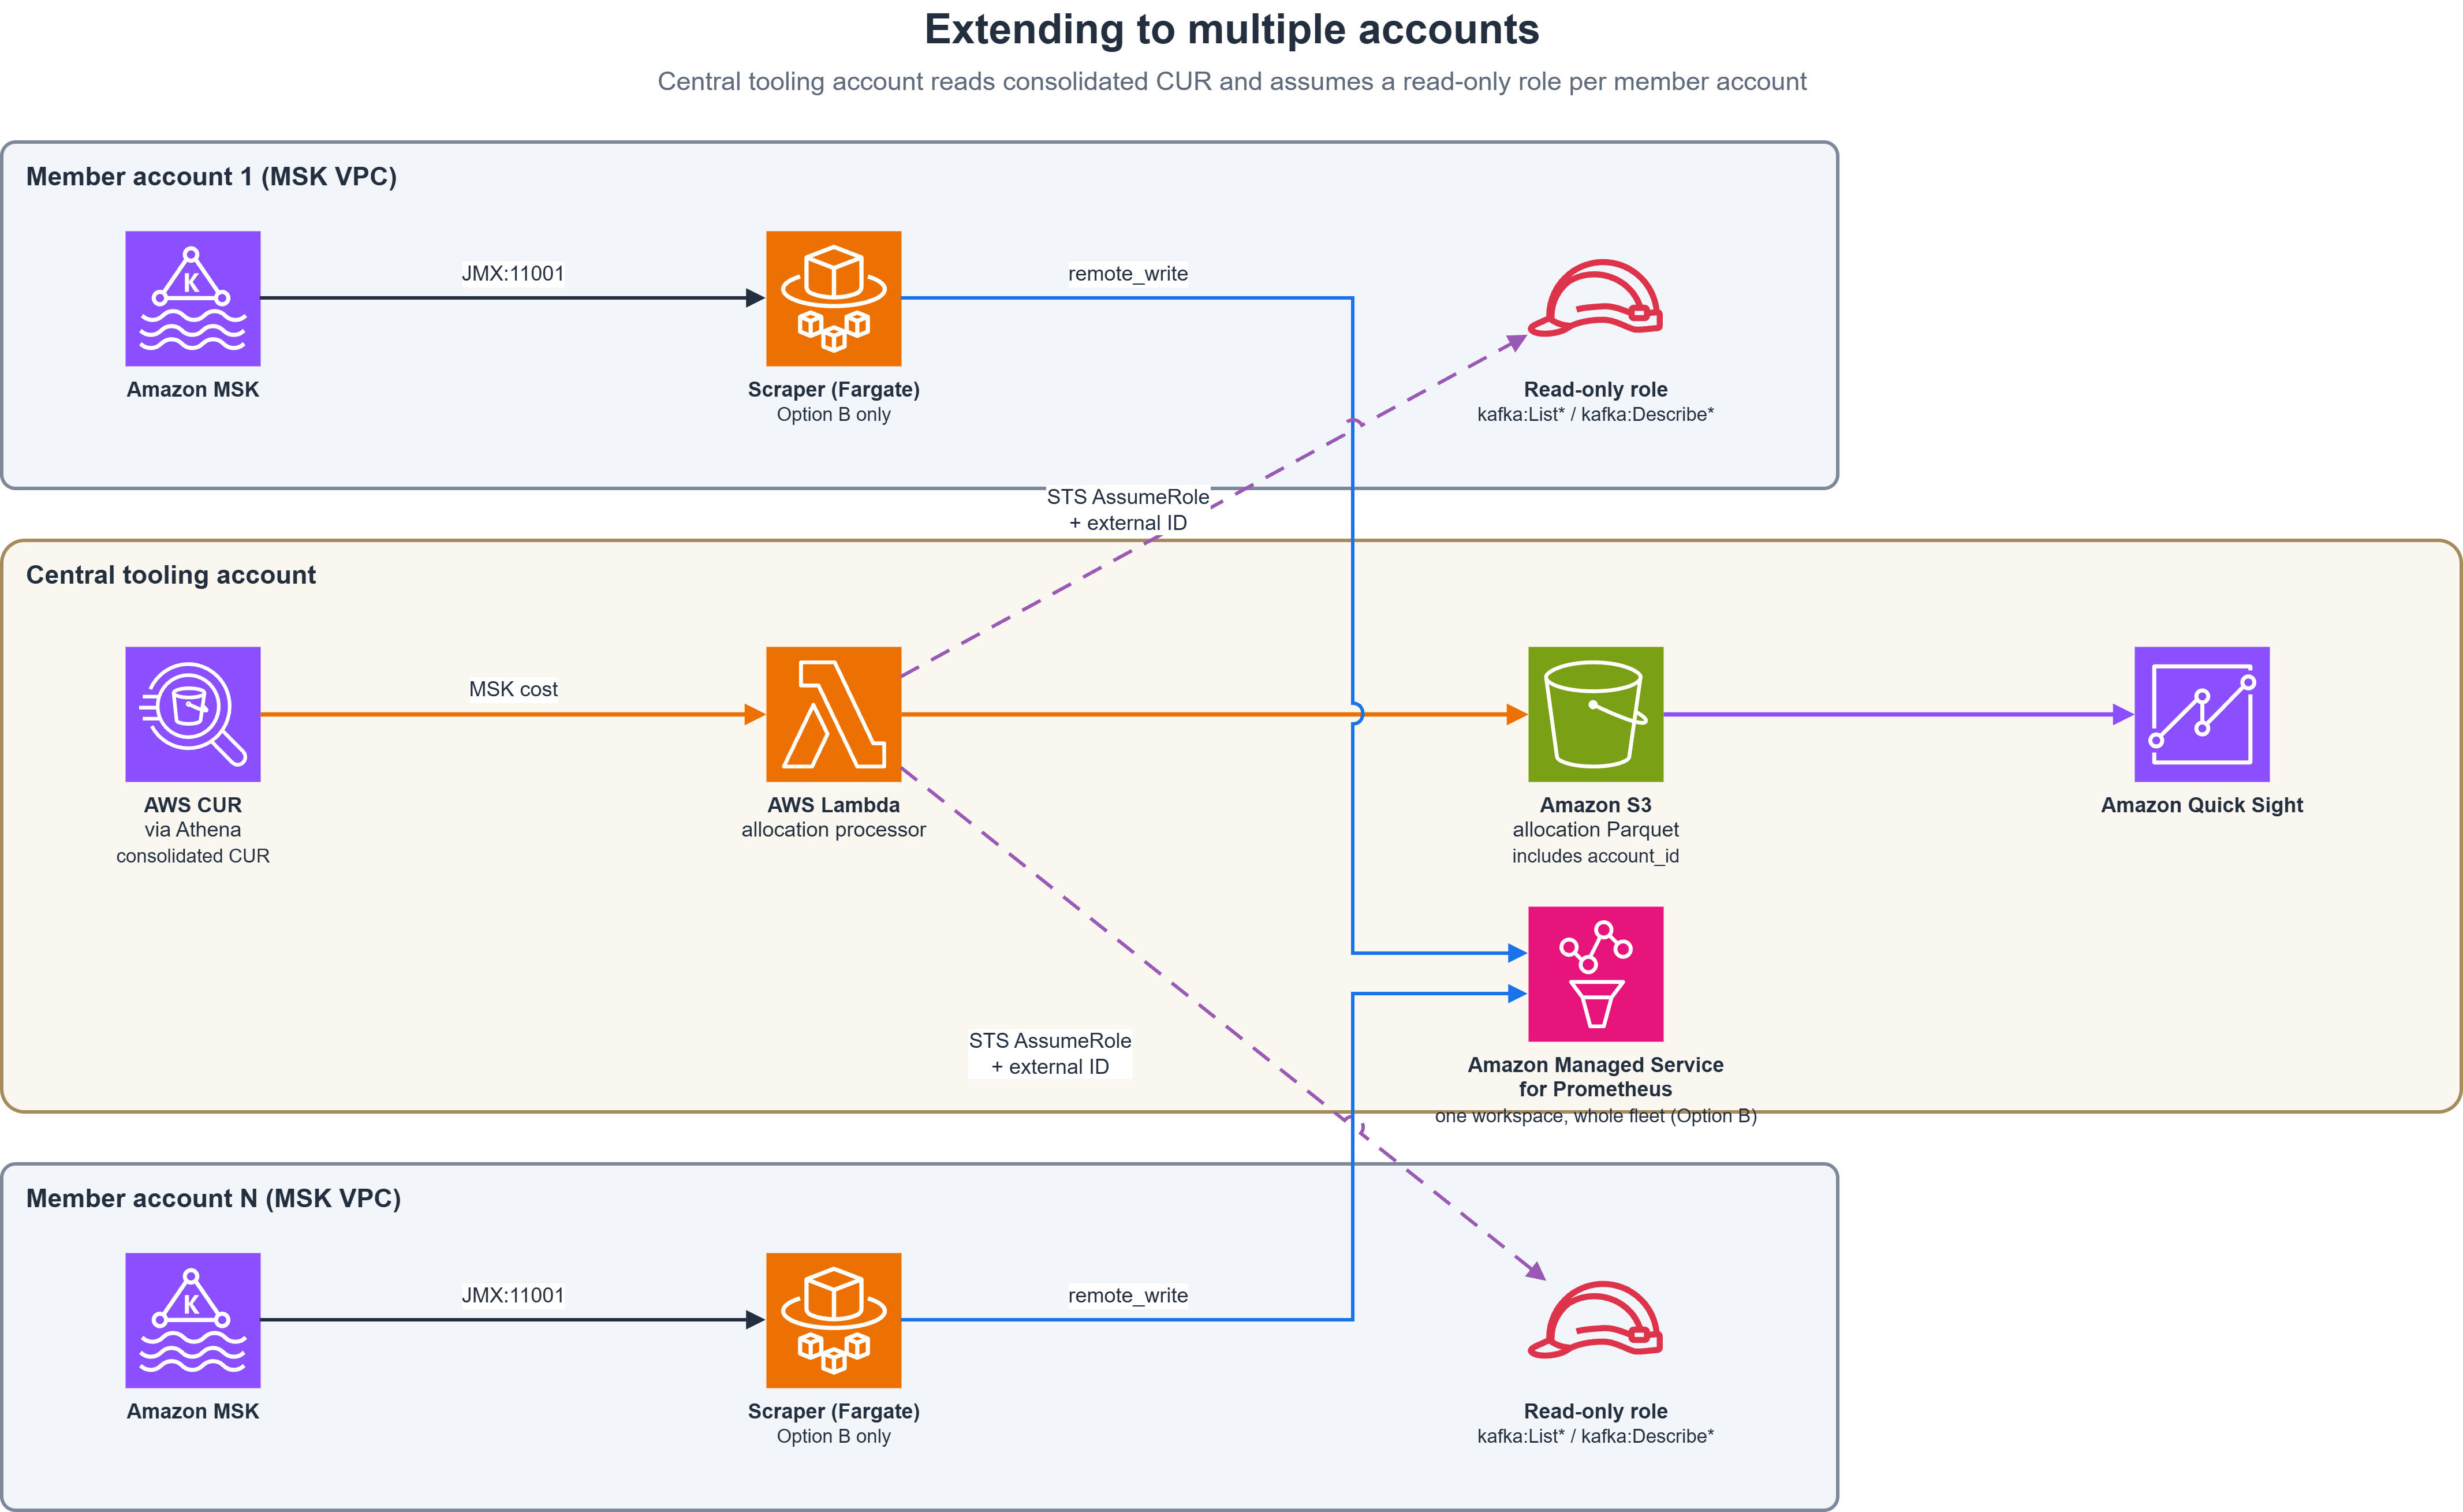
Figure 4: Multi-account extension. The central tooling account owns the pipeline and reaches into member accounts through a scoped, read-only role
Security considerations
This pipeline reads billing data and crosses account boundaries.
Grant the central execution role only the permissions it needs to: read the CUR and Glue catalog, run Athena queries, write to the allocation S3 bucket, and assume member-account roles.
Member-account role is read-only. Require a shared external ID on every AssumeRole call to help mitigate the confused-deputy problem.
For Option B, restrict port 11001 to the scraper’s security group. Consider AWS PrivateLink for remote write.
Encrypt CUR, allocation output, and Athena results at rest using SSE-KMS (recommended for financial data). Use TLS to encrypt data in transit, including the scraper’s remote write and Athena connections.
The output reveals what every team spends. Treat the output bucket and Quick Sight dataset as financial reports.
Cost of running the solution
The pipeline itself is inexpensive (Lambda, Athena, S3, Amazon EventBridge are negligible). Two items dominate:
- The metric source: ~$90 (Option A) compared to ~$11 (Option B) per month on the example cluster.
- Quick Sight user licenses: frequently the largest cost, scaling with how many people get access.
Clean up
To avoid ongoing charges, remove the resources you created. Delete Athena query result files and the CUR delivery configuration if created solely for this solution.
If you enabled Enhanced Monitoring solely for this solution, return to the previous level. For Option B, remove the scraper and Prometheus workspace.
Conclusion
This pipeline bridges cluster-level CUR cost to topic-level usage, giving each team visibility into its share of the spend. Switch between monitoring options with one environment variable. Pick a cluster and run the allocation to get started.
Learn more:
- Monitoring an Amazon MSK cluster – For monitoring levels and Open Monitoring setup.
- Amazon Managed Service for Prometheus – For workspace configuration and ingestion.
- Querying Cost and Usage Reports using Amazon Athena – For CUR table setup.
- Using Amazon Athena data with Quick Sight – For the reporting layer.
About the authors
Test your applications against AWS locally with AWS Emulator
Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/test-your-applications-against-aws-locally-with-aws-emulator/
Today we’re announcing AWS Emulator, a local emulator for Amazon Web Services (AWS) that you run on your machine. The AWS Command Line Interface (AWS CLI), the AWS SDKs, and your coding agents speak to it over a local HTTPS endpoint using the same AWS APIs they would use in the cloud, from your laptop. AWS Emulator has no additional service fee. You pay only for AWS resources when you deploy on AWS. Its source is on GitHub. You install it from an RPM or Debian package on Linux, and on macOS and Windows you run it in Docker.
How it works
You install the emulator, start it, and point your tools at the local endpoint. When AWS Emulator starts, it generates its own credentials, a config file, and a certificate, and writes them to ~/.aws/emulator/9297/. You set environment variables so the AWS SDK talks to your laptop instead of AWS, and your application code stays unchanged.
From there, your existing tests, CLI scripts, and coding agents keep working the way they already do. A unit test that creates an Amazon DynamoDB table, writes an item, and reads it back is the same test, and it runs on your machine without a deployment. A coding agent can create resources, check the result, and iterate again without waiting on a deployment in a Region.
The emulator is implemented in Rust so that it stays light on CPU and memory on a laptop. It supports the APIs of AWS services that have an API model in the AWS API models repository on GitHub, and because it’s built from those models, the same ones the AWS SDKs use, your requests and the errors you get back have the same shape as on AWS.
If you are a developer, especially one working with coding agents such as Kiro or Claude Code, you can use that loop to test AWS interactions of real complexity locally.
Let’s try it out
To get started, I installed the package on Amazon Linux 2023. The package adds the aws-emulator command to /usr/bin/, so it’s on the path.
PKG=https://downloads.aws.com/aws-emulator/packages/aws-emulator/LTS/latest
sudo dnf install -y $PKG/aws-emulator-x86_64.rpm

aws-emulator -v
On macOS and Windows, you build a Docker image from the short Dockerfile in the documentation and run the emulator in a container. We don’t publish a ready-made image.
I started the emulator with aws-emulator. It serves HTTPS on 127.0.0.1:9297, so only my own computer can reach it, and it writes its log as JSON lines that show the address, the config file, and the certificate file.
aws-emulator
In another terminal, I set the environment variables that point the AWS CLI at the emulator, and unset any variables that could supply real AWS credentials.
export AWS_ENDPOINT_URL=https://127.0.0.1:9297
export AWS_SHARED_CREDENTIALS_FILE=~/.aws/emulator/9297/emulator_credentials
export AWS_CONFIG_FILE=~/.aws/emulator/9297/config
export AWS_EC2_METADATA_DISABLED=true
export AWS_DISABLE_HOST_PREFIX_INJECTION=true
export AWS_REGION=us-east-1
export AWS_DEFAULT_REGION=us-east-1
unset AWS_ACCESS_KEY_ID AWS_SECRET_ACCESS_KEY AWS_SESSION_TOKEN AWS_PROFILE
The emulator generates new keys each time it starts. Its access key IDs start with EMULATOR, so you can’t mistake them for real AWS keys, and it rejects requests signed with any other keys. To confirm that my shell was talking to the emulator, I checked the health endpoint and the caller identity. The emulator uses a single account, 000000000000.
curl --cacert ~/.aws/emulator/9297/ca.pem https://127.0.0.1:9297/__admin/health

aws sts get-caller-identity
Then I created a bucket, copied in a small object, and listed it.
$ aws s3 mb s3://local-getting-started
make_bucket: local-getting-started

$ echo "hello from the emulator" > hello.txt

$ aws s3 cp hello.txt s3://local-getting-started/
upload: ./hello.txt to s3://local-getting-started/hello.txt

$ aws s3 ls s3://local-getting-started/
With the AWS CLI pointed at my laptop, I had the same commands I already use and a local endpoint that answered them.
Next I wanted to see it the way I actually work now, so with the emulator still running I opened Kiro and asked it to create an Amazon DynamoDB table, write an item, and read it back, all against AWS Emulator rather than my AWS account.
kiro> Using the local AWS Emulator (the environment variables
      are already set in this shell), create a DynamoDB table
      "kiro-demo" with a string key "id", put an item
      {id: "item-1", msg: "hello from kiro"}, then read it
      back with get-item.

$ aws dynamodb create-table --table-name kiro-demo \
    --attribute-definitions AttributeName=id,AttributeType=S \
    --key-schema AttributeName=id,KeyType=HASH \
    --billing-mode PAY_PER_REQUEST

$ aws dynamodb put-item --table-name kiro-demo \
    --item '{"id": {"S": "item-1"}, "msg": {"S": "hello from kiro"}}'

$ aws dynamodb get-item --table-name kiro-demo --key '{"id": {"S": "item-1"}}'
To use the same setup with an existing test suite, I would start the emulator, set the same environment variables in the script that runs the tests, and run them as usual.
Using the emulator in process
Running the emulator as a local process gives you an HTTPS endpoint that works with the AWS CLI and the AWS SDKs through environment variables. Some SDKs need an extra setting to trust the emulator certificate, for example a trust store for the AWS SDK for Java. For tests, there is a second option. AWS Emulator ships an embedded mode that you instantiate directly inside your test process and wire into the SDK through its HTTP client, rather than talking to a separate server over the network. Each embedded instance keeps its own state, so tests do not share buckets, tables, or queues, and you can run many of them in parallel. Embedded mode is available for the AWS SDK for Rust. You add the aws-emulator-embedded crate from GitHub to the [dev-dependencies] section of your Cargo.toml file. The following example creates an Amazon DynamoDB table, writes an item, and reads it back, entirely in process.
use aws_emulator_embedded::{AwsEmulatorEmbedded, EmbeddedOptions};
use aws_sdk_dynamodb::types::{
    AttributeDefinition, AttributeValue, BillingMode, KeySchemaElement, KeyType,
    ScalarAttributeType,
};

#[tokio::test]
async fn put_then_get_returns_the_item() {
    let emulator = AwsEmulatorEmbedded::new(EmbeddedOptions::default());
    let config = aws_config::defaults(aws_config::BehaviorVersion::latest())
        .http_client(emulator.http_client())
        .region(aws_config::Region::new("us-east-1"))
        .credentials_provider(emulator.aws_credentials_provider())
        .load()
        .await;
    let ddb = aws_sdk_dynamodb::Client::new(&config);

    ddb.create_table()
        .table_name("emulator-demo-table")
        .attribute_definitions(
            AttributeDefinition::builder()
                .attribute_name("id").attribute_type(ScalarAttributeType::S)
                .build().unwrap())
        .key_schema(
            KeySchemaElement::builder()
                .attribute_name("id").key_type(KeyType::Hash)
                .build().unwrap())
        .billing_mode(BillingMode::PayPerRequest)
        .send().await.unwrap();

    ddb.put_item()
        .table_name("emulator-demo-table")
        .item("id", AttributeValue::S("item-1".into()))
        .item("msg", AttributeValue::S("hi".into()))
        .send().await.unwrap();

    let got = ddb.get_item()
        .table_name("emulator-demo-table")
        .key("id", AttributeValue::S("item-1".into()))
        .send().await.unwrap();
    assert_eq!(got.item().unwrap().get("msg").unwrap().as_s().unwrap(), "hi");
}
When it runs as a local process, the emulator requires every request to be signed with Signature Version 4 (SigV4), the same way AWS does, and it exposes a /__admin/health endpoint on the same port so a script or a container can wait until it is ready before running tests. By default it also sends anonymous usage and error data, and you can turn it off.
How we measure fidelity
An emulator is only useful if a test that passes against it would also pass against AWS, so we measure that directly with fidelity tests. A fidelity test is a short program that uses an AWS SDK to run a workflow, such as storing an object and then reading and deleting it, and asserts how AWS behaves. We verify each fidelity test against real AWS. A fidelity test passes only if the emulator matches AWS on the response to every call, including the status code, the body, and the exact error code and message, and on the resources and data that the workflow creates.
With each release, we publish how many fidelity tests pass for each service, as k of n. For example, 40 of 50 means that 40 of the service’s 50 fidelity tests pass. The set of fidelity tests is public in the aws-emulator-evaluation-suite repository on GitHub, including the ones that don’t pass yet, so you can see what we verified and run the fidelity tests yourself. Read a score as a snapshot of a product that’s improving. When we add fidelity tests, a score can go down even while the emulator gets better.
If the emulator doesn’t implement an operation yet, it returns HTTP 501 (Not Implemented), so your tests fail right away. If the emulator acts differently from AWS, you can tell us by opening an issue in the AWS Emulator repository on GitHub.
How the emulator is built
AWS Emulator is built and maintained by agents from the AWS API models using Amazon Bedrock AgentCore Runtime Instances, AWS CodePipeline, and AWS CodeCommit, so it stays current with AWS as those models change.
One group of agents looks for gaps, both by comparing emulator responses against real AWS and by statically comparing the emulator’s code against the published Smithy models, and files an issue for each gap it finds. Another group picks up an issue, writes tests, implements the behavior, and reviews the change for correctness, performance, and security. When the change is ready, it is pushed to a source repository, and that push triggers an AWS CodePipeline run that runs the fidelity tests before the change is published to the public GitHub repository.
How we keep it secure
Because the code is written by agents, an independent security agent reviews changes adversarially, both while the fix is being made and again in the release pipeline as a final check before anything ships.
Security of your own use remains a shared responsibility. We build the emulator to run safely on your machine: it listens only on your own computer by default and rejects requests that aren’t signed with its own keys. You decide where it runs, what data you put in it, and how you test before production. Don’t use the emulator to test whether your application is secure. It doesn’t evaluate AWS Identity and Access Management (IAM) policies and resource-based policies the way AWS does, so a request that AWS denies might succeed in the emulator. Keep real credentials out of the environment of your test jobs, and test your security settings and your whole application on AWS before you go to production.
Now available
AWS Emulator is generally available today. It has no additional service fee. You pay only for AWS resources when you deploy on AWS. You can install it from RPM or Debian packages on Linux, run it in Docker on macOS and Windows, or build from source, and it works with the AWS SDKs and the AWS CLI once you set environment variables. At launch, it has some limits. It doesn’t evaluate IAM policies the way AWS does, and each emulator acts as a single account, with no cross-account or cross-Region behavior. How closely it matches AWS varies by service and feature. To see how well the emulator covers the services that you use, check the fidelity scores in the AWS Emulator documentation.
If you want to check regional availability, visit the AWS Capabilities by Region page in AWS Builder Center. If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this new feature, try using the AWS MCP Server and plugins with your preferred AI tool.
To get started, see the AWS Emulator documentation.
Part 4 – Cybersecurity journeys: What I’d tell my younger self
Post Syndicated from Shannon Brazil original https://aws.amazon.com/blogs/security/part-4-cybersecurity-journeys-what-id-tell-my-younger-self/
Over the past few weeks, I’ve introduced you to people who fell into security from the most unexpected places, who work in domains you’ve probably never heard of, and who were honest about what the job is like after the excitement fades and the real work begins. This is the final post in a four-part series following 11 Amazon Web Services (AWS) security professionals through the real stories of how they got here and what the work actually looks like. For this last one, I wanted to end where almost every one of my conversations ended up on its own: the things people wish they’d known sooner.
This one is about hard-won perspective, the kind you only get from doing the uncomfortable thing and coming out the other side. It’s about growth that doesn’t always feel like growth while it’s happening, and the advice these folks would hand to the earlier versions of themselves. If you’ve been with me since Part 1: I didn’t plan this, thank you for sticking around. I hope this last set of stories gives you something to carry into your own path.
Choosing the harder room
Justin Mills, Security Engineer
When I asked Justin Mills where someone should start, I expected a certification or a favorite course. His answer started with two words, “seek discomfort,” and his own career shows he means it. Justin is a security engineer with more than a decade in the field, and today he consults on how AI can strengthen security detections. Detections are the rules and models that watch a system’s activity and flag the signs of an attack, and both they and AI are changing faster than most of us can keep up with. What stuck with me was how much faster everything moved after he committed to doing the hard things: he earned two promotions in roughly 2 years.
So I asked him how, and his answer came back to the people around him. What surprised me was that he never went looking for them. Some came through luck, starting with the manager who hired him, and others arrived the way most good working relationships do: he got involved in projects, met the people on them, and the conversations just started flowing. He didn’t push or force any of it.
| “Those who are meant to be part of your career story will be part of it, no shoehorning needed.” —Justin Mills |
The other half of the equation was trust. Today, Justin works on hard problems, and his manager gives him room to work through them his own way, because he’s shown he can be trusted with that room. His manager even told him so directly: “I trust you to do the right thing and speak for us.” Earning that kind of trust changed how he approached the work. “That forced me to ask the right questions instead of defaulting to what I already knew,” he told me. There’s something important in that framing, because asking good questions isn’t a sign that you don’t belong; it might be the clearest sign that you do.
The lesson he had to learn later was almost the opposite of the one that got him started. Early on, growth meant taking on everything hard himself. As he moved up, it meant the reverse: learning to let go, treating delegation as a skill in its own right, and trusting the people on his team to carry work he could have gripped tightly. When I asked what he’d tell someone who feels stuck, he kept it short.
| “Surround yourself with people who push you, not people who make you comfortable. Ask the right questions. Do the hard things. That’s the whole playbook.” —Justin Mills |
Pandora’s box and a pile of dust
Tyler Gabor, Technician
Tyler Gabor has always been the person who takes things apart. He started out selling and fixing cell phones, learning what made them tick, before moving into help desk work. From there he made his way into data center operations, where the hardware went from handheld to industrial and the stakes scaled up with it. “If it lights up or makes noise, I’m messing with it,” he told me, and he meant it.
The jump from help desk to the data center came from preparation. While he was working help desk from home, Tyler studied for a few foundational certifications, and when he could show he knew what he was talking about, he started putting his name in for roles. One of those led to AWS, though not directly: a staffing agency he partnered with placed him on a temporary assignment there, and from that point he had to prove himself all over again to earn a full-time offer. He admits it wasn’t easy and was sometimes scary, and he compares the whole stretch to the Olympics, trying out for a spot on Team Amazon alongside some of the most talented people in the field. “It was the audition of a lifetime,” he told me.
When Tyler explains his work to people outside tech, he reaches for mythology. “It’s kind of like fixing Pandora’s box,” he said, “while also making sure that Pandora doesn’t get outside of the box.” It’s a vivid image for a job that involves testing, repairing, and sanitizing server hardware so the data a machine once held can’t resurface. That can mean wiping a drive, degaussing it (using a powerful magnetic field to scramble the stored data), or physically destroying it. This is security you can physically touch, and as he put it, “It’s a little hard to get intellectual property out of a pile of dust.”
What pulled him in wasn’t a degree program or a bootcamp. It was watching high-profile leaks and breaches dominate the news as a student, which made it clear that security wasn’t an abstract discipline but something shaping real events in the real world. That curiosity never faded; it’s the same impulse that has him tinkering with hardware side projects to this day, like programmable NFC chips (the same short-range wireless technology behind tap-to-pay cards) that he brings to hacker conferences as business cards. That same urge to see what a piece of hardware is really capable of shows up in his day job, too.
One project crystallized the stakes for him. A piece of hardware came through that most people would have assumed was safe to discard, and on closer inspection it was still holding information that should never have left the building. The lesson stuck with him, and he put it the way only Tyler would.
| “It doesn’t matter if the front door is locked if all the windows are open.” —Tyler Gabor |
What surprised me most, though, was how much he talked about leadership, not in the org-chart sense, but the quiet kind that shows up when your team trusts you to make the right call on your own. He didn’t expect to be trusted with hardware of this caliber, and you could hear how seriously he takes that responsibility. His advice for anyone early in their career, or thinking about the switch, sounds simple but clearly took time to earn: just ask for help, because when you do, people usually give it. And if you’re already in and feeling stuck, prepare for the role you want so you’re ready when it’s time to step up to the plate.
| “We are going to witness the greatest leap in human intelligence during our lifetime. As technology grows at an exponential speed, we’re going to need people to keep it in line.” —Tyler Gabor |
A short word from Zlata
You might remember Zlata Pavlova from Part 1, where she shared her path from political science to open source investigations and into protective security. I wanted to bring her back for a moment, because something she said has echoed through nearly every conversation in this series: the thing that holds people back is rarely a lack of skill, it’s the quiet suspicion that they don’t belong. Her answer to impostor syndrome is to remind yourself that you do and to build connections early. She spent years assuming her teammates already knew what she knew, and it turned out they often didn’t, because their focus was elsewhere. She also told me the biggest surprise of her current role was how much of it is writing, and especially how much of that writing means translating technical findings for readers who aren’t technical. As you move up in security, the reports, advisories, and briefs you write become one of the clearest signals of your judgment, so practicing that skill early, whether through a blog post, a conference talk, or simply explaining your work to a friend outside the field, pays off for years.
| “Don’t feel embarrassed sharing something you think people already know. They might not, and you might help somebody who’s just starting out.” —Zlata Pavlova |
The thread
Something I didn’t expect when I started this series was how often people’s earlier jobs turned out to be an advantage rather than a detour. Zlata told me that people who come into security from non-technical careers often explain things better, because they remember what it was like to need the explanation. Tyler’s years in telecommunications, where customers handed him phones that held their whole lives, are what first got him thinking seriously about protecting people’s information. And in Part 3, Brandon’s time administering systems and shipping software gave him the empathy for builders that his application security work depends on. The backgrounds people bring with them are part of why they’re good at this work.
If you’re early in your career and wondering whether you belong here, the people in this series would tell you that you do. If you’re mid-career and feeling stuck, pay attention to whichever story felt familiar, because that’s usually a clue about where to look next. And if this series showed you a corner of security you didn’t know existed, that corner might be a good place to start.
If you want to start, here are a few places to begin:
- AWS Skill Builder has more than 1,000 free self-paced courses, including security learning plans
- Navigating your way into cloud security maps the roles and skills across the field
- The NICE Workforce Framework for Cybersecurity lays out dozens of security roles and what each one needs
- Your local DEF CON group or a nearby security meetup, because community came up again and again in these conversations as the thing that speeds everything up
I’m grateful to everyone who sat down with me and shared their story. Hearing them changed how I think about what this field looks like, and I hope reading them does the same for you as you work out your own path.
What would you tell your younger self about getting into security? Share it on LinkedIn!
This concludes the Cybersecurity Journeys series. Read the full series: Part 1: I didn’t plan this, Part 2: What even is this job?, Part 3: The work behind the work, and Part 4: What I’d tell my younger self.
Zellij 0.46 released
Post Syndicated from jzb original https://lwn.net/Articles/1106903/
Version
0.46 of the Zellij terminal workspace has
been released.
This release includes a major addition in Zellij: Zellij is now also a
desktop terminal. To run it: zellij terminal. It works on linux, mac and
windows.Nothing changes for the normal multiplexer – Zellij can still run inside
another terminal. Both sessions are the same and can be shared.
Additional features in this release include a
GUI settings screen, session previews, and right-click menu. See this walkthrough
for more on the 0.46 release.
In Memoriam: Tim Peters 1952–2026
Post Syndicated from corbet original https://lwn.net/Articles/1106901/
Guido van Rossum conveys
the sad (and somewhat delayed) news of the passing of Tim Peters.
It’s hard to overestimate Tim’s influence on Python. He’s probably
best known for writing the Zen of Python (PEP 20), but to me he
was a mentor and language co-designer long before that.Tim found Python not long after its initial release. His first deed
was to convince me that Python should support mixed arithmetic
between int and float, because most users would expect them to work
that way. And he never stopped contributing.
Governance compliance beyond the catalog in Amazon SageMaker Unified Studio
Post Syndicated from Amom Luiz original https://aws.amazon.com/blogs/big-data/governance-compliance-beyond-the-catalog-in-amazon-sagemaker-unified-studio/
As your data catalog grows, how do you know which assets meet your organization’s governance standards? Amazon SageMaker Unified Studio provides the building blocks for governance such as metadata form definitions, data quality scores, glossary associations, subscription data, and a daily catalog export queryable through SQL.
A data catalog typically answers what exists as asset names, schemas, and ownership. SageMaker Unified Studio goes further, surfacing governance signals like metadata completeness, data quality scores, and glossary associations for each asset. This pattern brings them together into a single view you can query across all your assets, projects, and data products.
This post walks through how to build that enrichment pipeline and provide an asset scorecard example with an extensible set of dimensions and weights. However, the key takeaway is the pattern itself: after the signals are in one place, your team can define what “compliant” means for your context and manage assets and data products at scale. The pipeline is the foundation, and the business/compliance logic is yours to adapt and evolve.
The governance questions this pattern can answer include:
- Data Owner: Which of my assets are missing a required metadata form?
- Data Steward: Which assets have no glossary terms associated?
- Data Platform team/Managers: Is compliance improving since the team published the new governance rules, within and between projects?
- Chief Data Officer: Which departments need to work to provide more reliable data products to the organization?
This solution extends Analyzing your data catalog: Query SageMaker Catalog metadata with SQL, which introduced the asset metadata export feature. This post focuses on enriching the metadata export to support an enhanced and data-driven governance compliance strategy.
Solution overview
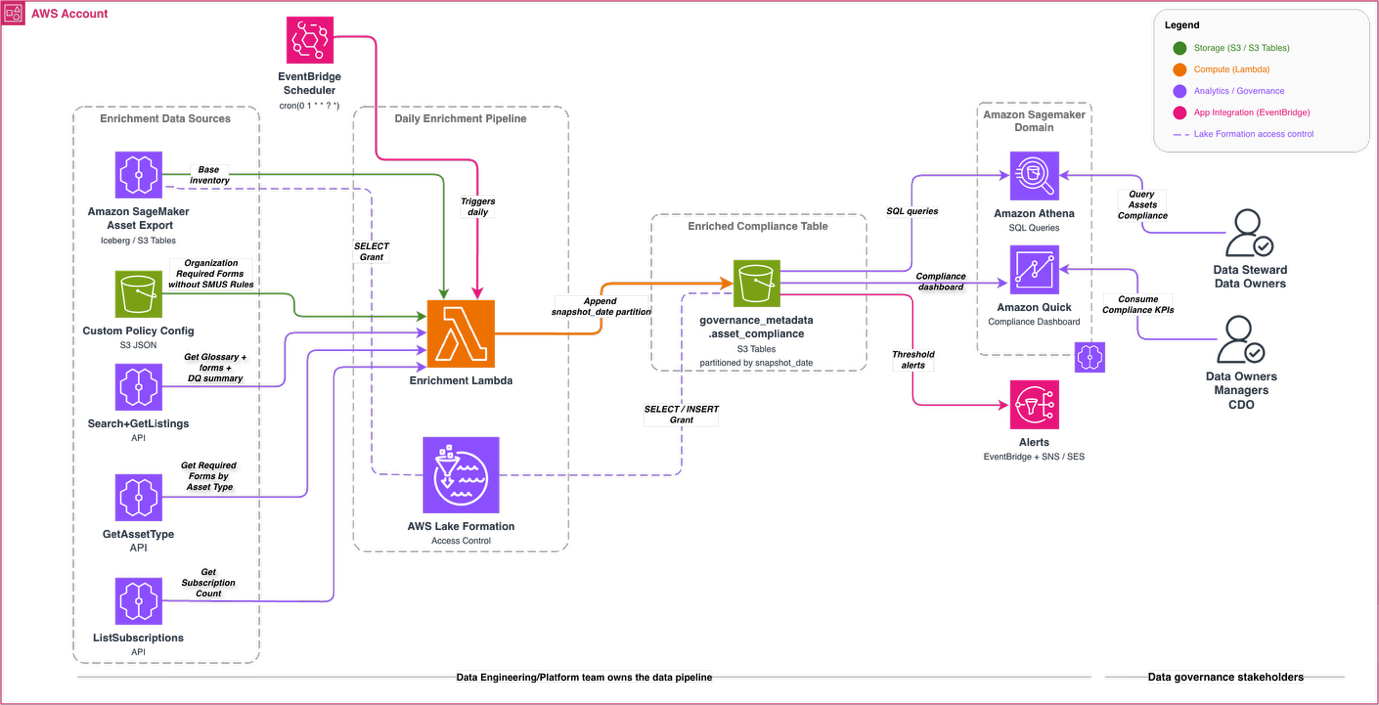
Figure 1: Daily governance enrichment pipeline, from the five data sources through the enrichment Lambda function to the Amazon Athena, AWS Quick Sight, and Amazon EventBridge consumers
The enriched compliance table is itself an Amazon Simple Storage Service (Amazon S3) Table asset in the SageMaker catalog queryable inside SageMaker Unified Studio alongside all domain assets.
The enrichment pipeline runs daily and consists of five data sources joined by an enrichment Lambda function:
- Amazon SageMaker Asset Metadata Export: the base inventory of all published assets, stored as an S3 Table.
- Form Policy Config: an S3 JSON file that defines custom organization-level required forms per project and asset type.
- Search / GetListing API: returns glossary terms, attached metadata forms, and a data quality summary per asset.
- GetAssetType API: returns the complete data quality rules count per asset.
- ListSubscriptions API: returns the number of active consumer subscriptions per published asset.
The pipeline reads from all five sources, computes a weighted compliance score per asset, and writes the result as a new daily snapshot partition to the governance_metadata.asset_compliance S3 Table. Downstream consumers such as Amazon Athena, AWS Quick Sight compliance dashboard, and Amazon EventBridge compliance alerts, read from that enriched table.
The following figure shows the end data product you will build: a compliance dashboard scoring every asset across your projects.
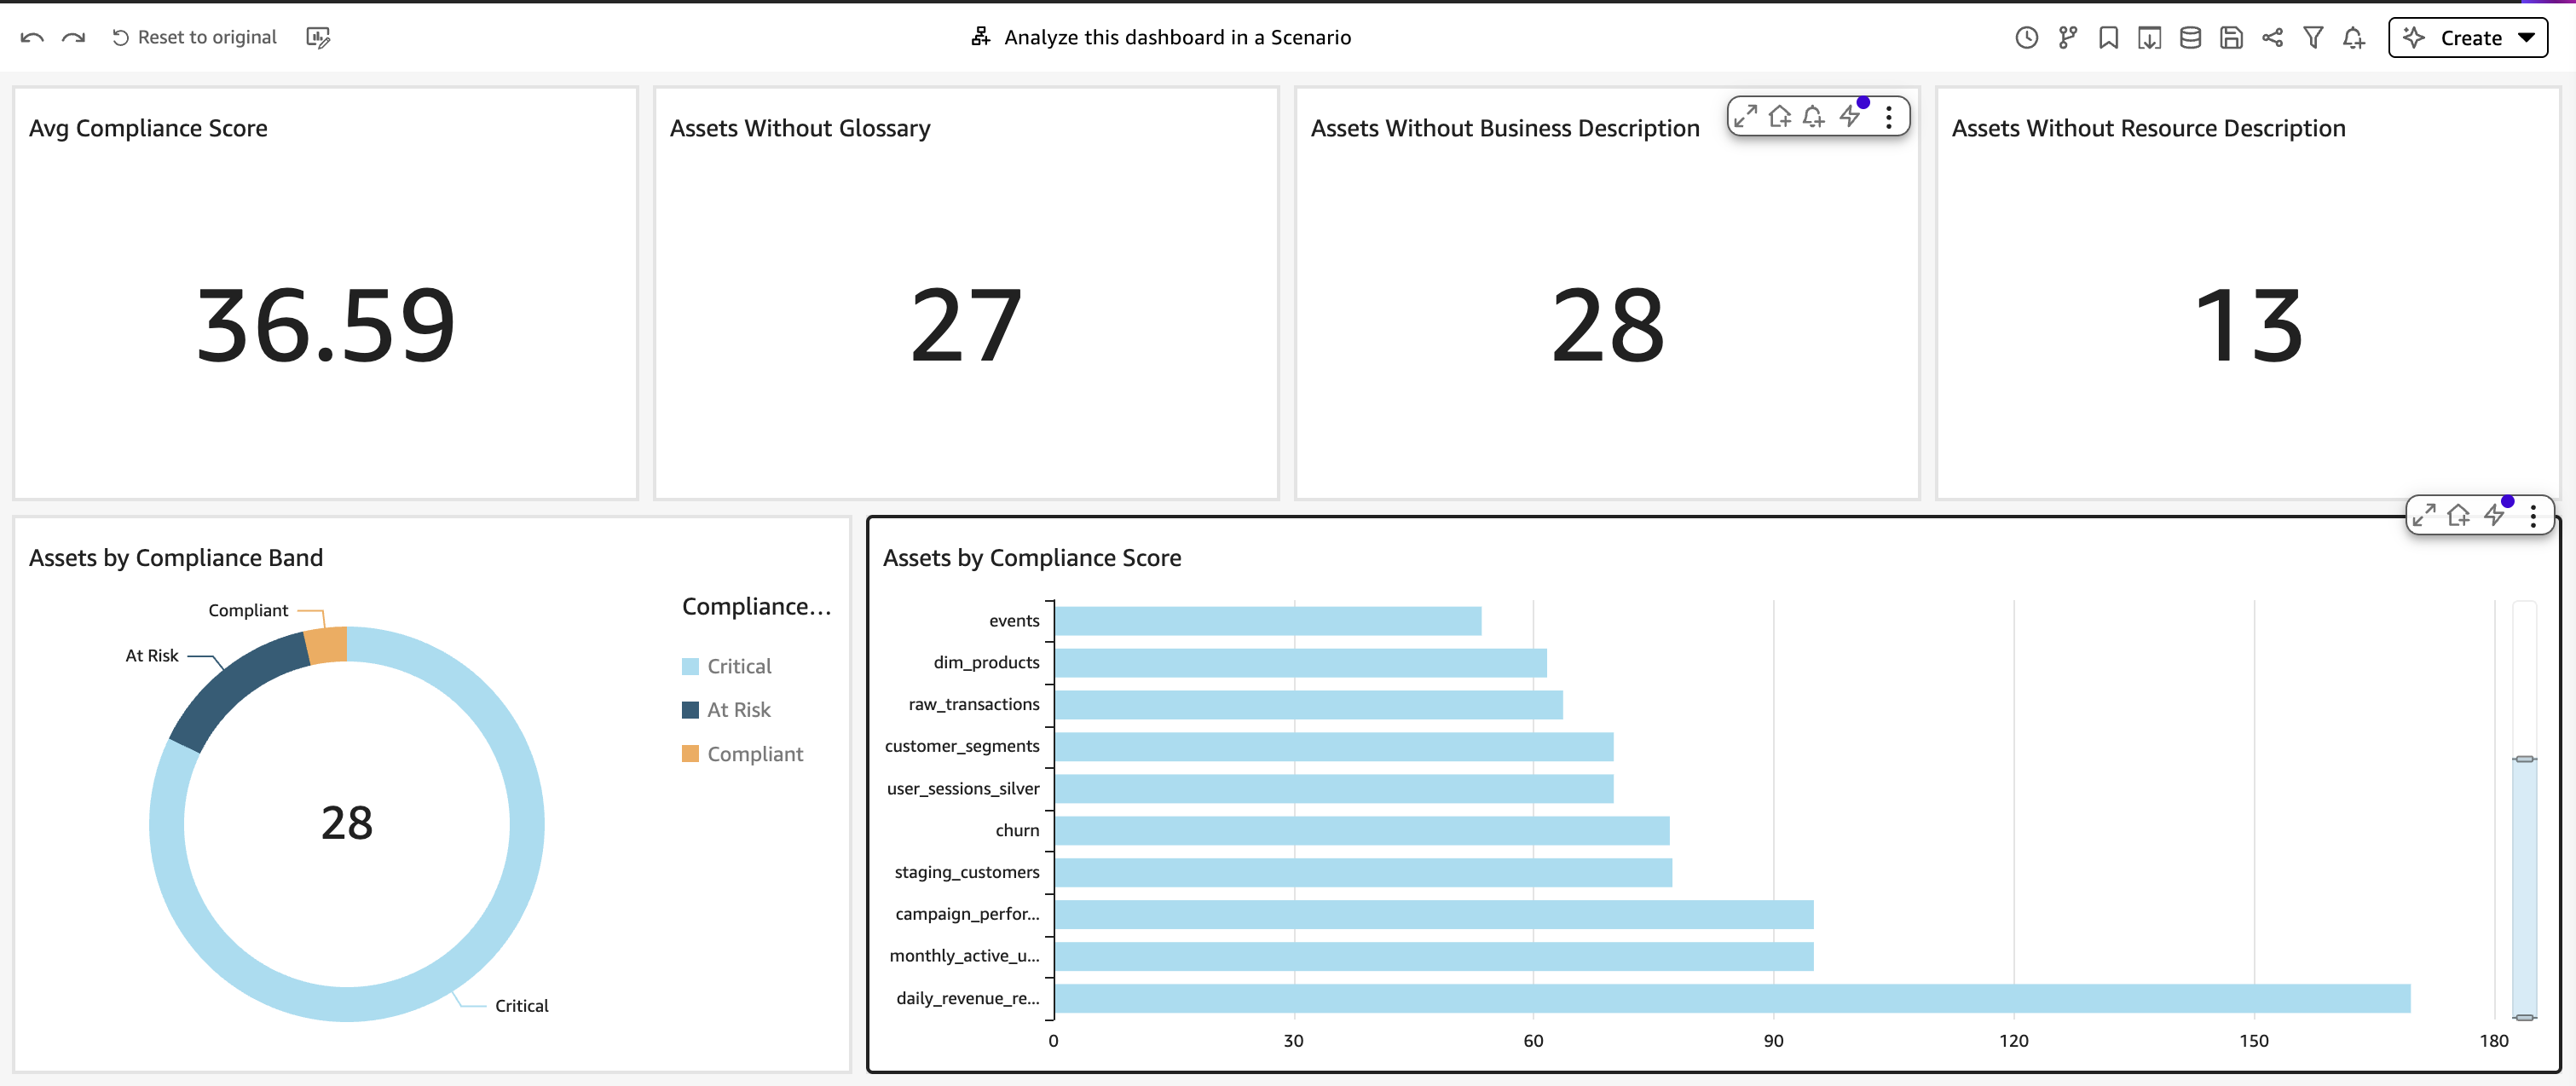
Figure 2: Compliance dashboard scoring every asset across your projects, the end product you build
Prerequisites
Before you begin, verify that you have the following in place:
- Python 3.12 and AWS Cloud Development Kit (AWS CDK) for deployment of the enrichment pipeline from the sample GitHub repository.
- An Amazon SageMaker Unified Studio domain. This post demonstrates the solution using an AWS IAM Identity Center (IDC)-based domain. You need permission to enable the asset metadata export on the domain (activating the export is covered in Part 1).
- Published assets in the SageMaker Unified Studio domain: the solution enriches information based on assets already published in the domain.
- An AWS account with permissions to work with the services used in this solution: AWS Lambda, Amazon Athena, Amazon S3 including Amazon S3 Tables, AWS Glue Data Catalog, AWS Lake Formation, AWS Quick Sight, and Amazon EventBridge.
- AWS Lake Formation access: The asset metadata export and the enriched table are governed by AWS Lake Formation, so you need to grant the Lambda execution role and the Amazon service role the appropriate DESCRIBE/SELECT permissions (detailed in the aws-samples repository).
- The AWS Command Line Interface (AWS CLI): configured for your account and target AWS Region.
- An AWS Quick Sight account in the same Region, required for the dashboard in Part 6.
Estimated time to complete is approximately 2 hours. Estimated cost is less than $5 per month for a small test domain (AWS Lambda invocations, Athena queries, and S3 storage). Costs scale with the number of assets and query volume.
Deploy the solution
The complete source code for this solution is available in the sample-smus-asset-scorecard repository on GitHub. The AWS Cloud Development Kit (AWS CDK) stack provisions all required infrastructure, including the enrichment Lambda function, Amazon S3 policy configuration bucket, Amazon EventBridge Scheduler rule, AWS Identity and Access Management (IAM) roles, and the S3 Table namespace. Follow the walkthrough available in the repository to deploy the solution.
Part 1: The asset metadata export
The asset metadata export serves as the primary data source for the enriched scorecard dataset. To activate the export once per domain, use the following AWS CLI command:
Within 24 hours you can read the asset metadata export as an S3 Table in SageMaker Unified Studio query editor (table asset_metadata.asset). You can check the Exporting Asset Metadata official documentation to get more details about the Asset Metadata export. Three fields from the export are used by the enrichment pipeline:
- asset_id: the identity of each asset in the catalog, and the join key the enrichment uses to map each row to its published listing (Part 3).
- extended_metadata[‘owningEntityId’]: this single key from the metadata map identifies which project owns the asset, driving the per-project compliance policy lookup in Part 2.
- business_description and resource_description: the documentation signals that contribute to the description dimension of the compliance score.
The following figure shows an example of the Asset Metadata Export:
Figure 3: Example of the asset metadata export queried in the SageMaker query editor
Part 2: The policy layer: Defining mandatory metadata forms
The export tells you what metadata form fields are filled. But required is a two-level concept in this solution:
Level 1: Amazon SageMaker Unified Studio metadata enforcement rules. You can configure mandatory metadata forms for publishing and subscription flows. These enforcement rules are defined at the asset-type level. You can call the GetAssetType API and inspect the required boolean in formsOutput.
Level 2: Custom organization-defined requirements. This solution also accounts for required metadata forms that lack enforcement rules, but your organization still considers mandatory. For example, a project might require a DataClassificationForm on every Glue table, even though SageMaker Unified Studio itself doesn’t enforce it at the asset-type level. These project-specific rules don’t exist as a native API endpoint, they can be stored externally in an S3 configuration file.
The enrichment pipeline reads both layers and takes their union. The SageMaker Unified Studio enforcement rules come from GetAssetType API per asset type and the custom organization-specific overrides come from a policy file stored in Amazon S3. Change the following sample file with the project IDs and required forms for your use case and put it in the S3 bucket created with CDK (see the Walkthrough section in the Readme of sample repository):
The S3 configuration file is updated whenever your governance policy evolves. The GetAssetType call ensures the pipeline always respects whatever enforcement rules are defined in SageMaker Unified Studio, including any new rules created in future revisions.
Part 3: The enrichment pipeline
The enrichment pipeline reads the latest export snapshot and joins it with governance facets from the published catalog through GetListing. It then merges the compliance policy from both enforcement rules (GetAssetType) and the custom organization-defined policy file. The complete implementation with annotated code is available in the aws-samples repository.
The enrichment Lambda reads the latest asset metadata export, calls the APIs for the dimensions not present in the export (data quality scores and glossary associations), and writes one enriched compliance record per asset.
3.1 The compliance score
The compliance score combines five independent dimensions, each contributing a weighted percentage as the following table shows:
| Dimension | Weight | Signal |
| Form coverage | 50% | % of required forms present compared to policy |
| Data quality score | 20% | Data quality pass/fail percentage |
| Data quality rule coverage | 10% | Actual rules compared to minimum expected |
| Glossary presence | 10% | Has at least 1 glossary term |
| Description | 10% | Has a business or resource description |
Weights and the minimum data quality rules threshold are configurable. Adjust them to reflect your organization’s governance priorities.
3.2 Run the enrichment pipeline
To run the pipeline, invoke the Lambda function as shown in the following example:
Part 4: The governance answers
With the enriched table available, the governance questions listed at the beginning of the post can be answered using SQL queries against the enriched table.
4.1 Assets missing required forms
The following query returns the list of assets missing required forms:
Figure 4: Query result listing the assets that are missing required metadata forms
4.2 Compliance scorecard per project
To explore the scorecard grouped by project, run the following query:
Figure 5: Per-project compliance scorecard aggregation
4.3 Compliance trend since rule publication
To answer how your assets are evolving since you published new rules you can run the following query:
Figure 6: Compliance trend across daily snapshots since the governance policy was published
Part 5: Alerting on non-compliant assets
You can go further and use Amazon EventBridge Scheduler combined with AWS Lambda to send weekly reports and alert your team when compliance drops below a defined threshold:
You can configure the Amazon EventBridge Scheduler rule to fire on a weekly schedule or daily if your organization requires tighter compliance monitoring. The send_governance_alert function is illustrative and can be routed to any channel your team prefers: Amazon Simple Notification Service (Amazon SNS) topics, Amazon Simple Email Service (Amazon SES), or a Slack webhook through an HTTP call.
Part 6: Building a governance dashboard with AWS Quick Sight
With the enriched governance table producing daily compliance scores, the final step is making these insights visible to stakeholders through an actionable and interactive dashboard. AWS Quick Sight connects directly to Amazon Athena, so you can visualize the compliance table directly.
6.1 Connecting and configuring AWS Quick Sight with the enriched table
Grant the AWS Quick Sight service role (aws-quicksight-service-role-v0) Lake Formation DESCRIBE and SELECT permissions on governance_metadata.asset_compliance. You can see details of grants needed in the aws-samples repository. In the repository you also can see a Python script which creates AWS Quick Sight data source, datasets and a complete dashboard with the compliance data, as the following figure shows:
Figure 7: Compliance dashboard connected to the enriched table in AWS Quick Sight
Figure 8: Per-project comparison charts in the governance dashboard
6.2 Create visualization using natural language
Use the natural language Build feature in AWS Quick Sight to create each visualization with a plain-language prompt:
| Visualization | Natural language prompt | Purpose |
| Compliance scorecard | “Show average overall_compliance_score by project_name as a bar chart” | Per-project accountability |
| Compliance band distribution | “Show count of asset_name by compliance_band as a pie chart” | Executive summary |
| Score trend over time | “Show average overall_compliance_score by snapshot_date as a line chart” | Is governance improving? |
| Form gap breakdown | “Show count of asset_name where missing_required_forms is not empty by project_name as a stacked bar” | Which teams have metadata form gaps? |
| Glossary coverage | “Show count of asset_name where glossary_terms_count equals 0 as a KPI” | How many assets have no terms? |
| Data Quality coverage | “Show average dq_rules_count by project_name as a bar chart” | Which projects lack data quality rules? |
Figure 9: Building a visualization with a natural language prompt in the AWS Quick Sight analysis editor
Figure 10: Natural language prompt interpreted as average compliance score by project
This produces an AWS Quick Sight dashboard built on top of the enriched table that delivers actionable governance, not raw metadata counts. Stakeholders see compliance scores, form gaps, and improvement trends without needing to understand the underlying API model.
Figure 11: Average overall compliance score by project rendered as a bar chart
For a deeper walkthrough of the natural language Build approach applied to the raw export table, see Build governance dashboards for Amazon SageMaker Catalog with AWS Quick Sight. The same technique applies to your enriched compliance table with the richer signals added by this pipeline.
Part 7: Seeing the pipeline in action
To illustrate how to apply these concepts, consider a domain with 20 published AWS Glue table assets across three projects, each at a different governance maturity level. After the daily enrichment runs, querying the compliance table immediately surfaces the differences.
7.1 Per-project scorecard
Briefly, you can see which teams are investing in governance and which ones need attention. The marketing-analytics leads because its assets have metadata forms, glossary terms, and data quality rules configured, while the other two projects have only basic data quality checks in place.
Figure 12: Per-project scorecard with compliance score and compliance band distribution
7.2 Drilling into individual assets
Based on compliance score defined previously as example, you can see the governance maturity into clear bands:
| Score | Band | Typical profile |
| 80–100 | Fully governed | All required forms present, glossary terms linked, data quality passing, description provided |
| 60–79 | Mostly governed | Required forms present, but missing either glossary terms or data quality coverage |
| 40–59 | Partially governed | Some required forms missing, or forms present but no glossary or data quality |
| 20–39 | Data quality only | Data quality rules configured and running, but no governance forms, glossary, or description |
| 1–19 | Minimally documented | Only a description present, but no forms, no data quality rules, no glossary |
| 0 | Ungoverned | No forms, no glossary, no data quality rules, no description |
The pipeline produces this output automatically on every scheduled run without manual intervention required. The Amazon EventBridge Scheduler fires daily, enriches the latest snapshot, and writes the compliance scorecard to the Iceberg table. A single Athena query then produces the per-project, per-asset view shown here.
Scalability note: in our test scenario with a domain of 29 published Glue Table assets across three projects, the enrichment Lambda completed in approximately 30 seconds. For organizations with larger domains and production environment, consider parallelizing asset enrichment calls and increasing Lambda memory allocation. For very large catalogs, a fan-out pattern using AWS Step Functions can distribute the workload across multiple Lambda invocations.
7.3 Consumption-weighted risk: who is using ungoverned data?
Compliance scores tell you what is below the required threshold. But not all compliance findings carry equal urgency. An asset with a score of 10 that five projects depend on might require immediate attention. The enrichment pipeline adds a subscription count per asset which represents the number of projects that have an approved subscription to consume it. This comes from the ListSubscriptions API, filtered by subscribedListingId (every published asset has a listing). Combined with the compliance score, it produces a risk matrix, as the following example shows:
| Quadrant | Compliance | Subscriptions | Recommended Action |
| Gold standard | >= 80 | High | No action: well governed and well adopted |
| Over-invested | >= 80 | Zero | Review: strong governance on unused assets |
| Backlog | < 50 | Zero | Plan: low risk, improve over time |
| Critical | < 50 | >= 2 | Act now: many consumers depend on ungoverned data |
The risk-view query joins both columns:
Figure 13: Risk query joining compliance score and subscription count to prioritize ungoverned assets
This turns your governance dashboard from a passive scorecard into a prioritization engine and asset teams know exactly where to focus based on both compliance gaps and downstream impact.
7.4 Extending to data products
With SageMaker Unified Studio, data producers can group related assets into data products, which are versioned, self-contained packages aligned to a business use case. Data consumers subscribe to a data product in a single request and receive access to all its member assets at once.
With this structure, you can aggregate compliance at the data product level. Build an asset_id -> data_product_name mapping by iterating over all projects. The data product scorecard query then rolls up compliance metrics across all assets in each product:
Figure 14: Data product compliance rollup across projects
This produces a compliance view at the level data consumers need: the products they subscribe to. A data product with a compliance score of 15 out of 100 and three subscriber projects is a potential governance incident, not a backlog item.
Cleaning up
If you deployed this pipeline in a test environment, delete the following resources to avoid incurring ongoing charges:
- The enrichment Lambda function and its associated IAM role.
- The Amazon EventBridge Scheduler rule.
- The
governance_metadataAWS Glue database and theasset_complianceS3 Table. - The S3 policy configuration file and any associated S3 bucket.
- The AWS Quick Sight dataset and analysis (if created).
- The Lake Formation permissions granted to the AWS Quick Sight service role.
The aws-samples repository has the commands needed to run the cleanup.
Conclusion
This post showed how to build a governance observability pipeline using Amazon SageMaker Unified Studio metadata exports and APIs, computes weighted compliance scores, and surfaces actionable governance insights through SageMaker Unified Studio queries and an AWS Quick Sight dashboard.
Amazon SageMaker Unified Studio provides the building blocks for governance such as asset type definitions, metadata form fields, data quality scores, glossary associations, subscription data, and a daily catalog export. This post demonstrates how to join those signals within Amazon SageMaker Unified Studio into a single enriched dataset to enhance data governance at scale.
The specific scoring model implemented here considering the five dimensions, their weights, and the risk classification by consumption is not prescriptive, but a starting point. Your organization’s governance policy might weight data product coverage more heavily, treat regulated project assets differently, or define “compliant” with a different threshold. The pipeline itself is the reusable part: after the signals are together, the scoring logic is yours to define and evolve.
Have questions about implementing this governance pipeline in your environment? Share your thoughts in the comments below or visit the aws-samples repository to contribute.
About the authors
Can Republicans Quit Trump? | The David Frum Show
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=FGAKXhp90eg
4 Home Assistant Marketplace Projects Worth Trying!
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=k9_FPbDHUo8
Pete Hegseth & Christian Nationalism #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/-iN0IVjOvjM
Track SMS spend by team and use case with AWS End User Messaging
Post Syndicated from Rommel Sunga original https://aws.amazon.com/blogs/messaging-and-targeting/track-sms-spend-by-team-and-use-case-with-aws-end-user-messaging/
If you send SMS for several teams or applications from one AWS account, you’ve probably been asked which team drove last month’s bill. The bill and the default AWS Cost Explorer view show one total for AWS End User Messaging. Grouping by usage type doesn’t help when teams send to the same country with the same type of origination identity, because their message fees land on one line. So each month, someone splits the bill by hand in a spreadsheet.
In this post, we show how to attribute AWS End User Messaging SMS spend to the teams, cost centers, and use cases that generate it. We walk through tagging your origination identities, activating those tags for cost allocation, and reading the results in Cost Explorer. Every step uses the AWS Management Console, and we include the equivalent AWS Command Line Interface (AWS CLI) commands if you want to script the setup.
This post is for FinOps practitioners, platform owners, and solutions architects who run shared SMS workloads and need showback or chargeback by team.
Challenges with tracking SMS spend
Organizations that send SMS for several teams from one AWS account commonly face these challenges:
- The bill and the default Cost Explorer view report AWS End User Messaging as a single service, with no split by team or application.
- Grouping by usage type shows what you paid for, such as message fees by destination country and origination identity type, but not who sent the messages.
- When two or more teams send to the same country with the same type of origination identity, their message fees combine into one usage type line. For example, three sender IDs that all send to the United Kingdom share one line.
- Finance teams need a monthly showback or chargeback report that they can rerun without manual spreadsheet work.
To address these challenges, you can tag each origination identity with the team and use case that owns it, and then activate those tag keys as cost allocation tags. Cost Explorer can then group your SMS spend by any of those keys, and the same tags flow into your AWS Cost and Usage Report (CUR) and AWS Data Exports.
Solution overview
Cost allocation for AWS End User Messaging SMS works at the level of the origination identity. Phone numbers, sender IDs, and phone pools are AWS resources with their own Amazon Resource Names (ARNs), and each one can carry up to 50 tags. When you send a message from a tagged phone number or sender ID, AWS records the charges for that message against that resource, along with its tags. The monthly fee for a tagged phone number carries its tags too.
The process has four stages, and each stage maps to one or more of the steps in this post:
- Tag your origination identities (Steps 1 and 2) – Assign each phone number and sender ID a set of tags, such as
business-unit,cost-center, anduse-case. - Send traffic (Step 3) – Messages from your tagged identities generate charges that carry the tags. New tag keys can take up to 24 hours to appear in AWS Billing and Cost Management.
- Activate the tag keys (Steps 4 and 5) – In the management account of your organization, or in a standalone account, activate the keys as cost allocation tags. Activation can take up to another 24 hours.
- Analyze (Steps 6 and 7) – Group your SMS spend by tag in Cost Explorer, or use the tags in your cost and usage reports.
Cost Explorer places charges that don’t belong to a tagged resource in the untagged group, a group that it labels No tag key: key-name.
The following diagram illustrates how the charges from a tagged sender ID reach Cost Explorer.
Figure 1: Each business unit sends from its own tagged sender ID. After the business-unit key is activated, Cost Explorer splits SMS spend by team. Charges from identities or resources without the key appear under No tag key.
Example scenario
Throughout this post, AnyCompany runs three business units that send SMS from one AWS account. All three send to the United Kingdom, each with its own sender ID, so usage type alone can’t separate their spend. AnyCompany uses the following tagging plan.
| Origination identity | business-unit | cost-center | use-case |
| Sender ID 1 (United Kingdom) | retail | cc-4100 | order-notifications |
| Sender ID 2 (United Kingdom) | banking | cc-7250 | otp |
| Sender ID 3 (United Kingdom) | marketing | cc-3300 | promotional |
Prerequisites
Before you begin, make sure you have the following components and permissions in place:
- An AWS account with AWS End User Messaging SMS and at least one origination identity (phone number or sender ID) that you send messages from.
- Access to the management account of your organization in AWS Organizations, or a standalone account. Only these accounts can activate cost allocation tags. If your SMS runs in a member account, you tag the origination identities there, and the management account activates the keys and requests any backfill.
- Cost Explorer enabled. The management account sees costs for every account. A member account sees only its own costs, and the management account can turn off Cost Explorer access for member accounts.
- AWS Identity and Access Management (IAM) permissions to view and tag AWS End User Messaging SMS resources (
sms-voice:DescribePhoneNumbers,sms-voice:DescribeSenderIds,sms-voice:DescribePools,sms-voice:TagResource,sms-voice:UntagResource, andsms-voice:ListTagsForResource). If you use the AWS Resource Groups Tagging API, you also needtag:TagResourcesandtag:GetResources. - IAM permissions in the management account or standalone account to activate and backfill cost allocation tags (
ce:ListCostAllocationTags,ce:UpdateCostAllocationTagsStatus,ce:StartCostAllocationTagBackfill, andce:ListCostAllocationTagBackfillHistory), and to view Cost Explorer reports, such asce:GetCostAndUsage,ce:GetDimensionValues, andce:GetTags.
Step 1: Plan your tag keys
Decide your keys before you tag anything. Tag keys and values are case sensitive, so Business-Unit and business-unit become two separate keys in your cost reports. Pick one convention, such as lowercase with hyphens, and use it everywhere.
AnyCompany uses three keys: business-unit (which team owns this spend), cost-center (which budget to charge), and use-case (what the traffic is for).
A tag describes the resource, so a sender ID that two teams share can only carry one business-unit value. If you need to split spend between teams, give each team its own origination identity. To see spend for each origination identity, for example, when one team owns several sender IDs, add a key that names the identity, such as identity-name.
Don’t include sensitive information, such as customer names or phone numbers, in tags. Cost allocation tags appear in billing reports that many people in your organization can read.
Step 2: Tag your origination identities
The following steps tag a sender ID. The steps for a phone number are the same, starting from Phone numbers under SMS & RCS.
- Open the AWS End User Messaging console.
- In the navigation pane, under SMS & RCS, choose Sender IDs.
- Choose the sender ID that you want to tag.
- On the Tags tab, choose Manage tags.
- Choose Add new tag, and then enter a Key and Value. Repeat for each key in your tagging plan.
- Choose Save changes.
Figure 2: The Tags tab of a sender ID that has no tags yet. Choose Manage tags to add, edit, or remove tags.
Figure 3: The Manage tags dialog for the retail sender ID. Enter a key and value for each tag in your tagging plan.
If you send through a phone pool, tag every phone number and sender ID in the pool. Message charges carry the tags of the origination identity that sends the message, not the tags on the pool.
The AWS Resource Groups Tag Editor console doesn’t list AWS End User Messaging SMS resources, but the Resource Groups Tagging API supports them. To tag many identities at once, use the TagResource operation with the AWS CLI or an AWS SDK, or the Tagging API. For examples, see Automate with the AWS CLI later in this post.
Step 3: Send traffic and wait for the tag keys to appear
Send messages from your tagged identities as usual. A new key can take up to 24 hours to appear on the Cost allocation tags page. You can’t activate it until it does, but you can attribute charges from that period with a backfill in Step 5.
If a key still isn’t listed after 24 hours, check the tag on the resource’s Tags tab. Also confirm that the key’s spelling and case match your plan, and that you’re signed in to the management account or standalone account.
Step 4: Activate the tag keys
- Sign in to the management account, or your standalone account, and open the AWS Billing and Cost Management console.
- In the navigation pane, choose Cost Allocation Tags.
- In the Cost allocation tags table, select
business-unit,cost-center, anduse-case. To find a key, enter it in Find cost allocation tags. Keys from tags on your resources have the type Resource. - Choose Activate.
Figure 4: The Cost allocation tags page showing AnyCompany’s three keys after activation.
After you activate a key, it can take up to 24 hours to become active in Cost Explorer. Activation applies from that point forward, so charges from before activation stay in the untagged group unless you backfill them.
Step 5 (optional): Backfill earlier months
If you tagged your origination identities before activating the keys, the management account can backfill up to 12 months.
- On the Cost allocation tags page, choose Backfill tags.
- Choose the earliest month in which your origination identities carried the tags.
- Choose Confirm.
Figure 5: The Backfill tags dialog. Choose the earliest month when your origination identities carried the tags.
A backfill only adds tag values for periods when the tag was attached to the resource. For example, if you tagged a sender ID on September 17 and request a backfill from September 1, charges from September 1–16 remain untagged. You can submit one backfill request every 24 hours, and Cost Explorer shows the results after its next daily data refresh. A backfill applies each key’s current status, so any key you’ve since deactivated is also removed from earlier months.
Step 6: View SMS spend by tag in Cost Explorer
- Open Cost Explorer.
- In the Report parameters panel, set Date Range and Granularity. For example, choose the last three months and Monthly.
- Under Group by, for Dimension, choose Tag, and then for Tag, choose your key, such as
business-unit. Group by with a tag key splits your spend into one line per tag value. A Tag filter only narrows the data to the values that you select. - Under Filters, for Service, choose End User Messaging, and then choose Apply.
Note: SMS carrier fees are billed under this service. The separate End User Messaging Third Party Fees service covers fees such as the WhatsApp fees that Meta charges.
From the management account, you can also filter by Linked account to see the costs of one member account.
Before any tagged usage is metered for a key, every charge sits in a single group, as shown in the following screenshot.
Figure 6: Cost Explorer grouped by business-unit for the months before the sender IDs were tagged. All AWS End User Messaging spend appears under No tag key: business-unit.
If you still see only No tag key more than 24 hours after activation, check that the key shows Active on the Cost allocation tags page. Also confirm that you’ve sent messages from a tagged identity since activation, or that you requested a backfill.
After the key is active and tagged usage has been metered, Cost Explorer shows one group for each tag value.
Figure 7: AnyCompany’s AWS End User Messaging spend for September, grouped by business-unit. Charges from resources without the key appear under No tag key: business-unit.
The No tag key group holds charges that have no value for the key. These include:
- Origination identities that you haven’t tagged yet, or that use a different spelling or case of the key.
- Other AWS End User Messaging resources that don’t carry the key, such as RCS agents.
- Messages sent over shared routes, which don’t use one of your origination identities.
- 10DLC registration fees, such as brand, vetting, and campaign fees.
- Charges from before the tag was attached or the key was activated.
To reuse this view each month, keep a relative date range, such as the last three months, and choose Save to report library.
Step 7: Combine usage type and tags
Group by Usage type to see what you’re paying for. Usage type names include the AWS Region prefix, the destination country, the origination identity type, and the type of charge, for example USE1-OutboundSMS-GB-Standard-Senderid-MessageFees. Message fees for all three AnyCompany United Kingdom sender IDs appear on this one line.
To split that line by team, set Group by to your tag key and add a Usage type filter for that line. The table then lists a costs row and a usage row for each tag value. To see only the cost rows, enter costs in the search box above the table.
Figure 8: United Kingdom sender ID message fees split by business unit, with Group by set to the business-unit tag and a Usage type filter applied.
Automate with the AWS CLI
If you manage many origination identities, or you want to add tagging to your provisioning scripts, you can run the same steps with the AWS CLI. Replace the example ARNs and account ID with your own. To list your ARNs, run aws pinpoint-sms-voice-v2 describe-sender-ids or aws pinpoint-sms-voice-v2 describe-phone-numbers.
To tag a sender ID when you request it, add --tags. The request-phone-number and create-pool commands accept the same option.
To tag an existing sender ID or phone number (Step 2), run the following command:
To apply the same tags to several identities in one call, use the Resource Groups Tagging API. Each call accepts up to 20 ARNs:
To check which sender IDs carry a key, filter by that key. For phone numbers and pools, use sms-voice:phone-number and sms-voice:pool.
To activate the tag keys (Step 4), run the following command in the management account or standalone account. If a key hasn’t appeared yet, the command returns a Tag keys not found error. Wait and try again, as described in Step 3.
To backfill earlier months (Step 5), set --backfill-from to the first day of a month, and then check the status of the request:
To get the monthly split by tag (Step 6), run the following command. In the API, the service name is AWS End User Messaging. Charges without the key are returned under business-unit$, which is the API form of No tag key.
To split a single usage type line by team (Step 7), add a USAGE_TYPE dimension to the filter, for example:
Going further
With your tag keys active, you can reuse them in other AWS Cost Management features:
- Budgets per team – Create an AWS Budgets cost budget filtered by
business-unitto alert each team when its SMS spend crosses a threshold. To receive those alerts on WhatsApp, see Establishing finops management: Integrating AWS Budgets with WhatsApp using AWS End User Messaging. - Anomaly alerts – Create an AWS Cost Anomaly Detection monitor for a cost allocation tag, so that an unexpected spike in one team’s SMS spend raises an alert for that team. Create the monitor in the management account, because monitors for cost allocation tags can only be created there.
- Chargeback reports – Activated tags are included in the cost and usage reports that you create with AWS Data Exports, so you can build monthly chargeback reports in Amazon Athena or your business intelligence tool.
Best practices for SMS cost allocation
- Tag origination identities when you provision them, so that the first message they send is attributed.
- Give each team its own origination identity when you need to split its spend.
- Tag every phone number and sender ID in a phone pool. Tags on the pool itself don’t appear on message charges.
- Use the same tag keys that your organization uses for other AWS services, so that SMS spend rolls up with the rest of each team’s costs.
- Review the No tag key group each month. If it grows, check for new origination identities that are missing tags.
Conclusion
By tagging your AWS End User Messaging SMS origination identities and activating those tags for cost allocation, you can see SMS spend by team, cost center, and use case next to the rest of your AWS costs. Tags also separate teams that send to the same country, which usage type alone can’t do.
Tag your identities and send traffic first, and then activate the keys after they appear. If you tagged before activating, backfill up to 12 months so that earlier charges are attributed too. Review the No tag key group each month to catch new identities that are missing tags. To build upon this foundation, consider adding per-team budgets and anomaly monitors on the same tag keys.
For additional implementation guidance and best practices, refer to the following resources:
- Tag AWS End User Messaging SMS resources for billing
- Manage tags for a sender ID in AWS End User Messaging SMS
- Manage tags for a phone number in AWS End User Messaging SMS
- Manage AWS End User Messaging SMS tags for phone pools
- Activating user-defined cost allocation tags
- Backfill cost allocation tags
- Filtering the data that you want to view in Cost Explorer
About the authors
Monitor application health with Amazon EC2 application status checks
Post Syndicated from Caroline Frost original https://aws.amazon.com/blogs/compute/monitor-application-health-with-amazon-ec2-application-status-checks/
Amazon Elastic Compute Cloud (Amazon EC2) application status checks monitor application health and responsiveness alongside instance, system, and Amazon Elastic Block Store (Amazon EBS) status checks. You can use them to identify a web server that has stopped accepting requests, a Docker daemon that is not running, an incorrect networking configuration, or a network interface that is no longer passing traffic. Amazon EC2 reports application, instance, system, and Amazon EBS status checks through the DescribeInstanceStatus API and Amazon CloudWatch, so you can monitor application health through these EC2 signals rather than publish a custom health metric.
Application status checks can monitor an EC2 instance whether it is launched using RunInstances, Amazon EC2 Fleet, or Amazon EC2 Auto Scaling. For RunInstances and EC2 Fleet, launch the instance with the tag used by the check association. EC2 reports the application status, and you choose how to respond. Amazon EC2 Auto Scaling monitors instance health and can use included application status checks to automate recovery by replacing an instance when its application status is impaired. When Auto Scaling launches a replacement with the app=database tag, the existing tag-based association includes it, so the application status check monitors the new instance without another association call. This walkthrough uses an Auto Scaling group and also covers CloudWatch alarms, staged onboarding, and application maintenance.
For additional details about the feature and pricing, you can refer to the What’s New post and application status checks in the Amazon EC2 User Guide.
Solution overview
Application status checks report through the DescribeInstanceStatus API and Amazon CloudWatch, so you can consume the result in more than one way. You can poll the status from your own tooling, alarm on the CloudWatch metric and run your own remediation, or rely on Amazon EC2 Auto Scaling to replace an instance whose application status is impaired.
In this example, we use the feature with EC2 Auto Scaling groups. Auto Scaling groups help you manage the instance lifecycle across launching, monitoring, and refreshing instances, and they maintain the number of running instances you specify by replacing an instance that fails a health check. For simplicity, we assume the group is a fixed size, with its desired, minimum, and maximum capacity set to the same value, so replacing an instance keeps capacity steady. We assume we have already set up application monitoring for an application running on EC2 instances in an Amazon EC2 Auto Scaling group. Our goal is to replace an impaired application quickly.
The walkthrough adds one application status check across your instances, surfaces the result in CloudWatch, and configures Auto Scaling to replace an instance whose application status is impaired.
You configure the protocol, port, path, accepted response codes, and failure and success thresholds. EC2 evaluates the endpoint every 60 seconds. A matching response code passes. A different response code, a refused or reset connection, or a timeout counts as a failure. The check reports failed after FailureThreshold consecutive failures and passed after SuccessThreshold consecutive successes. Both thresholds default to 2.
The application status of the instance is separate from the result of any single check. It is the aggregation of the checks associated with the instance that have Aggregation set to included. It reports impaired when at least one included check has a failed result. This is the value that appears as ApplicationStatus in describe-instance-status and that Amazon EC2 Auto Scaling acts on. An initialization grace period delays evaluation after launch, so an application that is still starting is not reported impaired before it is ready. You can associate more than one check with an instance, for example a liveness path and a readiness path, and include or exclude each one from the aggregated instance-level status.
Prerequisites
Before you start, you need the following:
- An application running on EC2 instances in an Auto Scaling group. If you need to create a group for this walkthrough, see Create an Auto Scaling group using a launch template. Configure the Amazon Machine Image (AMI) or user data in the launch template to install and start the application on each instance.
- A tag on those instances that you can target, for example
app=database. - Instances reachable on the health check port from within your virtual private cloud (VPC). With AWS-managed network paths, EC2 matches the health check source to the subnet and security group combinations used by the associated instances. Before creating the check, add an inbound rule to each instance security group that allows health check traffic on the check port from the same security group. The host firewall must also allow the port. The instances do not need public IP addresses.
- An AWS Identity and Access Management (IAM) principal with permissions for the EC2 application status check actions and EC2 Auto Scaling.
- Make sure your AWS Command Line Interface (AWS CLI) is up to date. Older releases might not include the application status check commands. If the CLI does not recognize
create-application-status-check, follow Installing or updating to the latest version of the AWS CLI before continuing.
If you do not have an application on a health path yet, add a lightweight endpoint that returns a success code when the instance is ready (most web frameworks expose one), or point the check at an existing readiness path. You need at least one running instance in the Auto Scaling group that is reachable on the check port and serving that endpoint to see a passing result.
To add a lightweight endpoint for an instance running Amazon Linux 2023, install nginx and serve a path that returns 200:
The final curl command confirms that nginx is listening locally and returning a 200 response. Before you create the application status check, configure the instance security group to allow health check traffic on port 8080 from the same security group. For instructions, see Security group referencing.
Create an application status check
Create a check that requests /health on port 8080 over HTTP and treats 200 as healthy. Keep the default thresholds and set an initialization grace period so that newly launched instances have time to start.
The response returns an application status check ID, for example asc-0123456789abcdef0.
Name=database-health identifies the application status check. The app=database tag used in the next step selects the instances to monitor.
The status code matcher defaults to 200 and accepts a comma-separated list of individual codes or ranges, for example "200,204", up to 64 characters.
Associate the check with your instances
Use the application status check ID returned by the create step to associate the check with every instance that carries the app=database tag. Tag-based association covers instances that already carry the tag and instances that launch with it later, which suits an Auto Scaling group where replacement instances launch with the tag.
You can also associate specific instances with --instance-ids instead of --target-tag-associations.
View the application status
The describe-instance-status call returns the application status alongside the instance and system status checks, so a query you already run surfaces it without a new API call.
The following example response shows a case where the system and instance status checks pass, while the application status reports impaired.
describe-instance-status returns the aggregation of the included application status checks associated with an instance. For details on every application status check associated with an instance, use describe-application-status, which returns each associated check’s individual result, the reason code, and the HTTP status code your application returned. Use describe-instance-status to see the aggregated application health next to other status checks, and describe-application-status for details on which check failed and why.
A failed check includes a reason that explains the outcome. For example:
For ResponseCodeMatched and ResponseCodeMismatch, the Reason includes the returned StatusCode and the Protocol, so you can distinguish a 500 from a 503. Connection reasons such as ConnectionTimeout, ConnectionRefused, and ConnectionReset indicate that the application did not complete a response at all, and do not include a StatusCode.
Replace instances with an impaired status check
When an application status check reports impaired, the right response depends on what failed, and not every impairment calls for terminating the instance. Common responses include rebooting the instance, rolling back a recent deployment, or terminating the instance and replacing it, and your workload may call for others. A transient fault may clear with a reboot, a bad deployment may call for a rollback, and a crashed or wedged instance usually calls for termination and replacement.
Amazon EC2 Auto Scaling evaluates the aggregated application status as part of its EC2 health checks. When the status is impaired, the group marks the instance unhealthy, terminates it, and attempts to launch a replacement from the group’s launch template. Auto Scaling does not copy the application from the terminated instance. Configure the AMI, user data, or deployment system for the group to install and start the application on each replacement. Because the group has fixed capacity in this example, it replaces the impaired instance rather than changing capacity. Auto Scaling includes application status checks in the group’s EC2 health checks by default, so no separate Auto Scaling health check configuration is required.
Terminate and replace is the default an Auto Scaling group gives you. If your remediation is a reboot or a rollback instead, keep the same impaired signal and act on it yourself, using the CloudWatch alarm in the next section to trigger your own automation.
Set the check’s InitializationGracePeriodSeconds to at least the time your application needs to start, and make sure the Auto Scaling group’s health check grace period is no shorter. Then neither the check nor the group acts on an instance that is still initializing. Detection and remediation then run without a separate monitoring system.
Alarm on the application status in Amazon CloudWatch
EC2 publishes the application status to CloudWatch, so you can alarm on it without a custom metric. This step is optional. Auto Scaling replaces an impaired instance whether or not you create an alarm. Add one when you want notification or a dashboard alongside the replacement. The following alarm notifies an operations topic when the application status check fails for an instance.
The alarm enters the ALARM state when the application status is impaired for three consecutive minutes. StatusCheckFailed_Application aggregates across every associated check whose aggregation is included. EC2 also publishes a per-check metric named StatusCheckFailed_Application_{application-status-check-id}, so you can alarm on an individual check when an instance has more than one associated.
To see the behavior end to end, stop the application process on one instance without stopping the instance. After the configured thresholds are met, the application status can turn impaired, the CloudWatch alarm can enter the ALARM state, and the Auto Scaling group can replace the instance while the remaining healthy instances can continue to serve traffic.
Rollout and maintenance strategies
Use the following strategies to stage deployment across your instances and suppress reporting during planned application maintenance.
Onboard checks across your instances
Roll application status checks out to a large number of instances in stages. An excluded check does not contribute to replacement decisions while you validate it.
Start in observe-only mode
Create the check with Aggregation set to excluded. An excluded check still runs and reports its result through describe-application-status and CloudWatch, but it does not contribute to the instance-level application status and does not cause Auto Scaling to replace an instance. Watch it for a representative period, confirm it returns the codes you expect, and tune the StatusCodeMatcher, FailureThreshold, SuccessThreshold, and initialization grace period. When you are confident, move the check to included with ModifyApplicationStatusCheck, and the result begins contributing to the instance-level status and to Auto Scaling replacement.
Associate by tag
Associate the check with a tag rather than a list of instance IDs. A tag-based association also covers a new instance when it launches with the tag, without another API call. This fits an Auto Scaling group, an instance refresh, or any workflow that replaces instances over time.
Amazon EKS and Karpenter
Application status checks can monitor an application endpoint on an EC2 worker node, including nodes launched for Amazon Elastic Kubernetes Service (Amazon EKS) managed node groups or by Karpenter. Each associated node must expose the HTTP or HTTPS health path on the configured port and carry the tag used by the check association. For an EKS managed node group, apply the tag to the EC2 instances through its custom launch template. For Karpenter, apply the tag through spec.tags in the EC2NodeClass. Application status checks monitor the endpoint on the EC2 instance, not a Kubernetes Service or an individual pod.
Manage checks as code
Define the check, its thresholds, and its tag association in the same infrastructure-as-code templates you use for your instances, so you can apply the same definition across environments and use your review process for changes. Roll the same definition out one Auto Scaling group or one Region at a time, and use a CloudWatch dashboard on the StatusCheckFailed_Application metric and the per-check StatusCheckFailed_Application_{application-status-check-id} metric to compare behavior before and after you switch a check to included.
The following template creates the check and its tag association. The template creates the check with Aggregation set to excluded so that it reports without contributing to the instance-level status, and you change it to included when you are ready.
The association takes the check ID, which the check exposes as an Fn::GetAtt attribute. To target named instances instead of a tag, use AWS::EC2::ApplicationStatusCheckInstanceAssociation with ApplicationStatusCheckId and InstanceId. Every ID property on both association resources is create-only, so changing the target replaces the association.
Run more than one check
You can associate more than one check with an instance, for example a liveness path and a readiness path, and include or exclude each from the aggregated instance-level status. Create a new check and exclude it from the aggregated count, confirm it behaves, then include it. The application status appears alongside the instance, system, and Amazon EBS status checks in describe-instance-status, so you can adopt it without changing the queries and alarms you already run.
Perform application maintenance
Planned maintenance, such as a rolling configuration change or a version upgrade, can make an application stop responding on its health path for a short time. Without a pause, the check reports the instance impaired and Auto Scaling can replace an instance that is healthy and only briefly offline. Pause reporting for the duration, then resume it.
The direct control is EnableApplicationStatusCheckSuppression. While suppression is in effect, the check does not mark instances impaired, so Auto Scaling does not act on it. Reporting resumes when you call DisableApplicationStatusCheckSuppression, or at the resume time set for the suppression. The following patterns wire that pause into common maintenance workflows.
EC2 Auto Scaling instance refresh and standby
An instance refresh rolls a new launch template through the group in batches and waits for each new instance to pass its health checks, including the application status check, before it continues. Set the check’s InitializationGracePeriodSeconds, and the group’s instance warmup, to at least the time your application needs to start, so the refresh does not act on an instance that is still initializing. For one-off manual work on a single instance, move it to standby with EnterStandby. The group stops health-checking and replacing it until you call ExitStandby.
AWS CodeDeploy
Suppression is not tied to any one deployment tool. If you deploy with AWS CodeDeploy, a deployment that restarts your application fails its health path until the new version is serving, so suppress the instance in a lifecycle hook before the deployment and resume it after. Suppress in a BeforeInstall hook and resume in an ApplicationStart hook in your appspec.yml:
scripts/suppress_status_check.sh suppresses the instance before the new version installs:
scripts/resume_status_check.sh resumes reporting once the new version is up:
The --duration-seconds value is a safety net: If the deployment fails before the resume hook runs, suppression lifts on its own rather than leaving the instance unmonitored. Omit it to suppress until you call disable. Grant the instance role ec2:EnableApplicationStatusCheckSuppression and ec2:DisableApplicationStatusCheckSuppression. After reporting resumes, the check evaluates the application again and returns the instance to healthy once it passes, so a routine deployment does not trigger a replacement.
AWS Systems Manager maintenance windows
For scheduled maintenance such as patching, run the work inside an AWS Systems Manager maintenance window and bracket it with the suppression calls: an automation step that enables suppression before the patch task and disables it after. Reporting stays paused for the window and resumes on its own at the suppression resume time if a step does not complete.
Clean up resources
Application status checks incur charges while they are associated with instances. AWS charges for each managed elastic network interface (ENI) AWS creates in your VPC, per Availability Zone, and standard Amazon CloudWatch rates apply to the metrics the checks publish. AWS creates one endpoint per combination of source subnet and security group, so the count does not scale per instance or per check. Delete the resources you created so that you do not incur further charges. Delete the application status check and the CloudWatch alarm, and delete the Auto Scaling group if you created it only for this walkthrough.
Quotas
Application status checks are subject to service quotas that cap how many checks you create, how many associations you make, and how many instances you monitor. Review the current defaults before you roll out to a large number of instances, because a tag-based association covers instances that launch later. A growing number of instances can reach a quota without any change to your configuration. Once you pass a quota, the instances beyond it stop being checked and report no status. Use the Service Quotas console to view usage and request increases. For the current quotas and how each one is counted, see Application status checks in the Amazon EC2 User Guide.
Conclusion
In this post, we showed how to monitor application health on Amazon EC2 with application status checks. You created an HTTP check, associated it with your instances by tag, viewed the status alongside your existing status checks, alarmed on it in Amazon CloudWatch, and relied on Amazon EC2 Auto Scaling to replace an impaired instance. You can use EC2 status checks and Auto Scaling to detect and respond to application failures rather than operate a separate monitoring system.
If you use another deployment mechanism, apply the association tag to each EC2 instance and make sure the application exposes the configured health path and port. Contact your AWS account team if you need help adapting this pattern to your deployment process.
To learn more, see Application status checks in the Amazon EC2 User Guide and Health checks for instances in an Auto Scaling group in the Amazon EC2 Auto Scaling User Guide. As a next step, add a second check for a readiness path and exclude it from aggregation to see how per-check status contributes to the instance-level result.
About the author
How Intuit migrated from Apache Hive Metastore to AWS Glue Data Catalog
Post Syndicated from Srinivasan Krishnasamy original https://aws.amazon.com/blogs/big-data/how-intuit-migrated-from-apache-hive-metastore-to-aws-glue-data-catalog/
Migrating from Apache Hive Metastore (HMS) to AWS Glue Data Catalog (GDC) is a priority for many organizations as they scale their data analytics operations. At enterprise scale, maintaining an efficient and reliable metadata management system becomes increasingly critical. Many enterprises started their big data journey with HMS, which has served as a reliable catalog service for storing table definitions and metadata. As cloud adoption has grown, so have requirements for fine-grained access control and for serverless, fully managed solutions. As a result, organizations are looking to modernize their data catalog infrastructure and are moving their metastores to GDC, a fully managed AWS metadata repository. With GDC, they gain native integration with various AWS analytics and AI services, along with centralized data management and governance.
In this post, we walk through how Intuit successfully migrated its extensive data catalog from HMS to GDC. This migration is part of Intuit’s journey to an open, secure lakehouse architecture for data and analytics. We explore the challenges Intuit faced and the solutions it implemented. We also cover the benefits that motivated the move: reduced operational overhead, improved data discovery, and enhanced integration with AWS analytics services. Whether you are considering a similar migration or exploring your options for metadata management, this real-world example provides practical insights into the migration process.
Migration considerations and prerequisites
- Audit the HMS catalog and remove unused tables and views by deleting or flagging them to filter out during initial migration to GDC. This will make sure that after migration you have a clean catalog and will help with better migration performance.
- Estimate the read and write API limits you will need in GDC based on the traffic in HMS. To do this, you can audit the internal HMS tables and get the P99 numbers for reads and writes to tables and partitions. These numbers will need to be translated to AWS Glue Data Catalog API limits and the necessary quota increase requests will need to be submitted. Load test with these quotas to confirm that they support your peak read and write rates without throttling, and implement retries to handle any throttling that does occur.
- Make sure you have your AWS Glue quotas sized properly for your account and use case. You can work with AWS Support to increase these quotas based on the results of the load testing.
- Data is stored in Amazon Simple Storage Service (Amazon S3) for table resources that are planned for migration. Only databases, tables, and partitions can be migrated. Other entities, such as column statistics, privileges, roles, functions, and transactions, were outside the scope of the migration.
- Plan for table renames: In GDC table/database rename isn’t supported. In some cases, customers rename tables as part of their data pipelines to get atomic updates for tables that are non-partitioned and don’t use an open table format (OTF). For use cases where this pattern is required, we recommend writing to a new S3 location and then running the following
ALTER TABLEcommand to change the S3 location.
Architecture
The following diagram shows the overall architecture of the solution across two consumer accounts (spoke accounts), and a central data governance account as part of a hub-and-spoke architecture.
Figure 1: Solution architecture spanning the source and consumer spoke accounts and the central data governance account
In the source spoke account, Hive Metastore manages the metadata for data stored in Amazon S3. This is the current state. In the central data governance account, an HMS and GDC sync process propagates this metadata into the central AWS Glue Data Catalog, which AWS Lake Formation governs. AWS CloudTrail records operations on the central catalog. The central catalog is shared across accounts with the consumer spoke account. There, Amazon Athena, Amazon Redshift, and Amazon EMR query the data through role-based access, using Lake Formation and a local AWS Glue Data Catalog. This migration strategy is explained in detail in the following sections.
Migration strategy
At Intuit, the central team manages the data catalog and offers it as a platform for the different teams to use. Because of the scale of Intuit’s data lake and the large number of teams using the data platform, Intuit had to come up with a phased strategy. With these tenets in mind, Intuit came up with the following approach:
- One-time migration of all databases, tables, and partitions. During this phase all the objects were migrated from HMS to GDC. The migration will be point-in-time and any changes happening in HMS will not be captured by the initial migration.
- Ongoing sync from HMS to GDC to capture all changes happening in HMS and apply them to GDC. This would make sure any team that is ready to migrate their pipelines to GDC can do so without any dependency on upstream and downstream processes.
- Ongoing sync from GDC to HMS to capture any changes that happen in GDC and apply them back to HMS. Some of your pipelines might still point to HMS while the upstream pipelines whose tables they consume have already moved to GDC. This sync process replicates all changes back to HMS, so those pipelines aren’t impacted.
- To make sure both catalogs remain in sync and to prevent drift, a parity tool runs hourly to compare all critical metadata values and verify consistency between the catalogs. For details, see the Parity tool section later in this post.
- An ad hoc sync process was also built. If the parity tool identifies that the two catalogs are out of sync, this process provides a straightforward way to bring them back in sync.
To prevent a circular loop between the HMS-to-GDC sync (#2) and the GDC-to-HMS sync (#3), each table is assigned a single source of truth. The source of truth is recorded as a sourceCatalog flag (HMS or GDC) in an Amazon DynamoDB arbitration table. During the HMS-to-GDC incremental sync, only tables whose source of truth is HMS are picked up and synced to GDC. Conversely, the GDC-to-HMS sync checks the sourceCatalog flag to confirm the change genuinely originated in GDC and isn’t a cascading update that was originally synced from HMS. This arbitration model makes sure each table’s metadata flows in only one direction at any given time, eliminating the risk of circular updates between the two catalogs.
1. Initial full migration
The first step is to migrate all the databases, tables, and partitions from HMS to GDC. This will need to be planned over a weekend to make sure there is no impact on the workloads running on HMS. The duration of this initial migration will vary depending on the size of your data lake. After being customized to support batching and retries, the AWS Glue Hive metastore migration utility was used to migrate all the metadata (databases, tables, and partitions) from HMS to GDC.
This utility runs an AWS Glue extract, transform, and load (ETL) job that pulls the metadata from the Amazon Aurora MySQL tables that hold the HMS metadata. The job transforms the data and writes it to the AWS Glue Data Catalog.
The following diagram shows the one-time sync process.
Figure 2: One-time migration of metadata from Hive Metastore to AWS Glue Data Catalog
An AWS Lambda function starts the AWS Glue ETL job. The job settings, such as the number of workers and the database, table, and partition write factors, come from a cdk.json configuration file. The job reads databases, tables, and partitions from the HMS MySQL database over JDBC. It transforms them into DynamicFrames with batching and rate limiting, and writes them to the AWS Glue Data Catalog. Amazon CloudWatch captures job metrics and logs. The lower half of the diagram shows nine orchestration steps: stopping the incremental sync, cleaning up GDC, running full and delta syncs, and turning on the parity jobs.
Customization options
The utility should work as-is for most cases, but Intuit customized the script to speed up the one-time migration process while making sure that GDC didn’t throttle requests.
Loading behavior
Set catalog.overwriteIfExists to false during your runs.
This is a good approach for use cases with a large number of tables because it skips overwriting a table that already exists.
Rate limiting
One way to control the rate and reduce the amount of data sent to GDC is to change the value of catalog.ratePerDPUSecond in the code. This parameter adjusts the rate at which changes are written to GDC, and you can configure it as shown in the preceding code sample. The following formula shows how RatePerSecond is calculated and how catalog.ratePerDPUSecond influences it.
Worked example
With the defaults (catalog.ratePerDPUSecond = 10, DefaultExecutorsPerDPU = 2), each data processing unit (DPU) submits five calls/sec. At that rate, a 200-DPU job submits approximately 500 calls/sec (100 x 10 / 2) when the DataFrame is well partitioned. Lower catalog.ratePerDPUSecond or the DPU count until throttling stops. Internally, these writes call BatchCreatePartitions, which batches partition creation and keeps API volume down.
Handling API limits
In GDC, there are limits for each API call and if you exceed the limits you will be throttled. One approach to handling API limits is to batch the database, table, and partition loads and send the batched data during each batch.
In addition to batching, you should also implement an exponential backoff and retry strategy, as described in the post Managing and monitoring API throttling in your workloads.
2. Incremental load for bidirectional sync
The second step involved creating a two-way synchronization between HMS and GDC. This synchronization made sure that any changes made to tables in HMS were reflected in GDC, and vice versa. To maintain consistency, incremental data loads were necessary between the two systems. The process synced metadata changes by capturing updates in HMS and GDC and applying them to the other system. This kept both catalogs synchronized. A key rule was to designate one catalog as the definitive source of truth for each table to avoid conflicts. This was done using the DynamoDB arbitration table as described earlier.
HMS to GDC
The following diagram shows the ongoing incremental sync from HMS to GDC.
Figure 3: Ongoing incremental sync from Hive Metastore to AWS Glue Data Catalog
The ongoing incremental sync from HMS to GDC is powered by an event-driven architecture that propagates metadata changes in near real time. Catalog updates to the source HMS can affect databases, tables, table parameters, or partitions. A Debezium connector continuously monitors the underlying MySQL instance for any INSERT, UPDATE, or DELETE operations through Change Data Capture (CDC). This approach removes the need for polling or application-level hooks.
Captured changes are routed into dedicated Kafka topics based on the type of metadata object affected. HMS-HIVE-DBS receives database-level changes, HMS-HIVE-TBLS receives table-level changes, and HMS-HIVE-TABLE_PARAMS receives table parameter modifications. HMS-HIVE-PARTITIONS receives partition changes, and HMS-HIVE-SDS receives partition or table location change events. This separation allows each object type to be processed, scaled, and retried independently. For partitions specifically, a 10-second rolling window is applied per table. When the first partition event arrives for a given table, a 10-second timer begins, and all subsequent partition events for that table are collected. When the timer expires, all accumulated events are submitted as a single batch call to the SDK, which significantly reduces API throttling for tables with high partition churn.
Before any change is synced to GDC, the system performs a schema opt-out check against an Amazon DynamoDB table. This lookup determines whether the affected database or table has been explicitly excluded from synchronization, giving individual teams governance over what metadata flows into the central catalog. If the schema is opted out, the change is dropped and no sync occurs. If it isn’t opted out, the system proceeds to apply the metadata operation (create, update, or delete) to the central GDC through the AWS Glue SDK.
Sometimes additional metadata context is needed to fully resolve a change, for example, to construct a complete table definition when processing a partition update. In these cases, the system falls back to extracting metadata directly from HMS over a JDBC connection to the source Aurora MySQL database. This makes sure that GDC always receives complete and consistent metadata, even when the CDC event alone doesn’t carry all required fields.
The overall design achieves low-latency metadata propagation without placing read pressure on the source HMS. Together, the batching strategy, queue-based decoupling, and opt-out mechanism provide a scalable, governed, and throttle-resilient sync pipeline.
GDC to HMS
The following diagram shows the ongoing incremental sync from GDC to HMS.
Figure 4: Ongoing incremental sync from AWS Glue Data Catalog to Hive Metastore
The reverse sync from GDC to HMS follows an event-driven architecture. It captures metadata changes made in the AWS Glue Data Catalog and propagates them back to HMS to maintain bidirectional consistency.
When databases, tables, or partitions are added to or deleted from GDC, Amazon EventBridge detects the change through an EventBridge rule. This rule is configured to match specific change events (adding or deleting databases, tables, or partitions) and triggers an AWS Lambda function (handle-eventbridge-events) to begin processing the event.
The Lambda function publishes the raw events to an Amazon Managed Streaming for Apache Kafka (Amazon MSK) topic called central-gdc-raw-events. A downstream Apache Flink consumer, the Streaming Pipeline for Out of Order Raw Events, reads from this topic and applies event ordering logic. Because events might arrive out of sequence, this pipeline uses a one-minute rolling window to buffer events by schema or table. It then sorts the buffered events by their event timestamp and re-publishes them in the correct order to a second Amazon MSK topic called central-gdc-ordered-events.
At this point, the flow splits into two parallel consumption paths.
- The first path is consumed by another Apache Flink consumer, the
gdc-to-hms-syncpipeline, which is responsible for determining whether a given schema or table is allowed to sync. It performs a lookup against an Amazon DynamoDB table to check an allow list. If the entity is permitted for synchronization, the pipeline proceeds to push the metadata change to HMS using Amazon Athena as the execution engine. If the entity isn’t on the allow list, the pipeline takes no action and the event is dropped. - The second consumption path is consumed by a Data Lake crawler which updates the Data Lake control plane metadata inventory database.
The content of each ordered event is used as a trigger to get the latest metadata from GDC. That metadata is then synced to HMS by using the Thrift SDK and a Thrift client running on an Amazon EMR cluster.
The overall design reflects changes made in GDC reliably and consistently back into HMS. The event ordering pipeline applies operations in the correct sequence, regardless of delivery order. The allowlist mechanism in DynamoDB provides governance, because teams control which schemas participate in the reverse sync. Amazon Athena handles the final push to HMS by using its native integration with both GDC and Hive-compatible data stores.
3. Parity tool
When doing a migration through a bidirectional sync approach, a mechanism to do a parity check between the two systems is important to track any drift in the two catalogs. A parity tool was built to make sure the two catalogs are always in sync and to catch any discrepancies.
The following diagram shows the four stages of the parity tool pipeline: data extraction, data storage, comparison, and results.
Figure 5: Four-stage parity tool pipeline that compares the two catalogs
The parity tool uses AWS Glue jobs and Spark processing to efficiently compare catalog metadata:
- Data extraction:
- Primary list: Reads from DynamoDB table to determine which databases and tables to compare.
- HMS: Connects to HMS MySQL database to extract metadata for tables in the primary list.
- GDC: Uses AWS Glue API to extract metadata for tables in the primary list.
- Data storage:
- S3 output: Extracted data from both catalogs is written to S3 in Iceberg table format.
- Iceberg tables: External Iceberg tables are created, allowing for efficient querying and comparison using Spark.
- Comparison engine:
- Spark jobs analyzed the Iceberg tables to identify differences in:
- Databases exist in both catalogs.
- Tables exist in both databases.
- Table structures including columns and data types.
- Table locations and SerDe paths.
- Partition information including values and S3 location.
- View definitions.
- Spark jobs analyzed the Iceberg tables to identify differences in:
- Results and views:
- Difference tables are created showing objects present in one catalog but not the other.
- Aggregation views provide summary counts.
- Status views show parity health and sync status.
- History tables track changes over time.
4. Ad hoc migration
An ad hoc migration process was built to perform ad hoc migrations for specific databases, tables, or partitions. This makes sure that if there is a discrepancy identified by the parity tool, it can be mitigated without having to run a full sync process. The ad hoc migration is an enhancement to the utility used for one-time sync where it can take the database name, table name, and partition information as input. Depending on the input provided, it will sync the respective objects.
GDC table requirements
- S3 location: The location for the table data must be in S3. Only databases with an S3 location, or databases with one or more tables with an S3 location, will be included in the migration.
- S3 location name length: The S3 location name can be up to 701 characters.
- Table type: Only the HMS table types
MANAGED_TABLE,EXTERNAL_TABLE, andVIRTUAL_VIEWare being imported to GDC. - Non-blank column names: Every column must have a name.
- Column name length: Column names can be up to 255 characters. HMS allows 256.
- Column name characters: Column names must not include the following characters:
?,\n, and\\. - Column type name length: Column type names can be up to 131,072 characters (2^17).
Conclusion
Migrating metadata from HMS to GDC is a complex process, but it can enhance your data management capabilities. Intuit’s migration shows that moving from HMS to GDC requires careful planning and execution. It also shows that the benefits of a modern, cloud-native catalog service make the move a worthwhile investment for organizations that want to scale their data operations efficiently and securely. After migrating to GDC, Intuit is focusing on implementing strong access controls using row-level, column-level, and cell-level controls in AWS Lake Formation. Because Intuit is building complex solutions and applications, this level of fine-grained access control is critical. Getting its catalog migrated to GDC was an important step in this journey.
To plan your own migration, see the AWS Glue Data Catalog documentation and the AWS Glue Hive metastore migration utility on GitHub. For fine-grained access control, see the AWS Lake Formation documentation.
About the authors
Building a GPU workstation for visual effects with Amazon EC2: Part 5 – Security
Post Syndicated from Andy Hayes original https://aws.amazon.com/blogs/compute/building-a-gpu-workstation-for-visual-effects-with-amazon-ec2-part-5-security/
For many years Amazon Web Services (AWS) has been guiding users in the deployment of powerful NVIDIA GPU backed workstations for graphics intensive workloads. With the recent expansion of our G-series Amazon Elastic Compute Cloud (Amazon EC2) graphics-based instances, we’re excited to introduce new instance families that deliver enhanced performance and capabilities. We’re also refreshing our comprehensive guidance on choosing and configuring these powerful virtual workstations.
This is the fifth post in a five-part series, exploring security practices related to the deployment of visual effects (VFX) workstations: how to secure these workstations by controlling who can reach the desktop, protecting the session in transit, and safeguarding the credentials, images, and storage behind it. The following screen capture shows these GPU-powered workstations in use, in a real production environment.
Figure 1: Amazon EC2 GPU-powered workstations, used in a Studio-in-the-Cloud courtesy of Outpost VFX
Before you begin
This post builds upon topics covered earlier in the series, regarding Linux and Windows EC2 instances, configured for the purposes of creating GPU workstations.
If you want to understand more about GPU accelerated Amazon EC2 G graphics instances, go to Part 1 in this series: Build a GPU workstation for visual effects on Amazon EC2: Part 1 – Setup.
For deployment instructions for creating a Rocky Linux graphics workstation, go to Part 2 in this series: Building a GPU workstation for visual effects on Amazon EC2: Part 2 – Linux.
For creating a Windows Server 2025 graphics workstation, go to Part 3 in this series: Building a GPU workstation for visual effects with Amazon EC2: Part 3 – Windows.
Finally, for methods to standardize and optimize instances, for rapid re-use at scale, go to Part 4 in this series: Building a GPU workstation for visual effects with Amazon EC2: Part 4 – Optimizations.
Security considerations
When deploying EC2 instance workloads on Amazon EC2, security hardening isn’t only a best practice but also essential for protecting your infrastructure, data, and applications from evolving threats. AWS provides secure cloud infrastructure, but the responsibility for securing the operating system and applications running on your EC2 instances falls squarely on you as part of the AWS Shared Responsibility Model. While AWS secures the underlying infrastructure (the physical servers, networking equipment, and hypervisor layer), you’re responsible for everything from the guest operating system upward. This includes patching, configuration management, access controls, and monitoring. A misconfigured EC2 instance can become an entry point for unauthorized users, potentially impacting more than that single instance in your AWS environment through lateral movement.
Throughout this post series, we’ve implemented security best practices aligned with the AWS documentation on Best practices for Amazon EC2. As we conclude, let’s revisit the key security principles we’ve applied and explore additional considerations for production environments.
Amazon DCV connection security
Amazon DCV provides immediate out-of-the-box encryption of pixels and end-user inputs, and to do so it creates a self-signed certificate. As previously mentioned, the browser issues a security warning when you connect by default. This is expected because the browser can’t verify the certificate’s authenticity in terms of domain or validity by a Certificate Authority (CA). Amazon DCV doesn’t immediately know your domain requirements for servers or clients. You elect to accept the risk based on your knowledge of the IP in question that you are connecting to.
Amazon DCV itself has further configurations that can mitigate potential security risks. For example, the DCV server can perform administrator-defined regex filtering on origin and host names to protect against WebSocket hijacking, and Host Header attacks. On Linux, add the following to dcv.conf, typically found at /etc/dcv/dcv.conf:
On Windows, you add the respective string values for each parameter subkey within the Computer\HKEY_USERS\S-1-5-18\Software\GSettings\com\nicesoftware\dcv\security registry key. The following screen capture shows this registry key open in Registry Editor, with the connectivity-restriction values in place. In this example, two values are defined under the security key (allowed-ws-origin-regex and allowed-http-host-regex) each set to a regular expression that limits connections to a specific domain.
Figure 2: The Amazon DCV registry security key, with subkeys limiting host and origin connectivity
For more information about security parameters with Amazon DCV, see security parameter reference of the Amazon DCV Administrator Guide.
Amazon DCV clients requesting connections to the Amazon DCV server can be restricted through fundamental network-level controls that allow requests from specific IP addresses and ports:
- AWS Network Access Control List (ACLs) restrict inbound and outbound traffic at the subnet level on the VPC.
- AWS Security Groups (as already mentioned and used in this post) apply another layer of restrictions on incoming IP addresses and ports to the server instance.
- Firewall rules can further restrict incoming IP addresses and ports.
To extend both the functionality and security of Amazon DCV, an Amazon DCV Connection Gateway can also be used as part of a more extensive infrastructure, to act as an intermediary between clients and servers. From a security point of view, it adds a single point of entry, hiding the servers behind the gateway, mitigating load, but also implementing a token-based authentication system to resolve server sessions for clients.
Whilst these steps prevent unauthorized access attempts from unexpected sources, it doesn’t solve the certificate trust warning. To improve both the user experience (to resolve the warning, and the general question of is this secure?) as well as strengthen your security defenses, consider using your own certificate from a trusted CA. This is beyond the scope of this post, but services such as AWS Private Certificate Authority provide the ability to create certificates that encapsulate your domain and can be trusted by the browser as a legitimate CA. Not only does this simplify the user experience but it also provides cryptographic verification of server identity and protection against man-in-the-middle attacks.
Network security
We have repeatedly applied the principle of least privilege, using Security Group rules to restrict access to known IP addresses only. As detailed in Part 1 of this series, the choice of connectivity method significantly impacts your security architecture, and while this post uses internet connectivity for simplicity, production environments should evaluate additional security layers based on their requirements. Network Access Control Lists (NACLs) can also be used for subnet-level traffic filtering as an additional defense layer to security groups, and AWS Network Firewall offers advanced threat protection and intrusion detection.
For enhanced security postures AWS Site-to-Site VPN adds network-layer IPsec encryption on top of the application-layer security of Amazon DCV, protecting against man-in-the-middle attacks, traffic analysis, and DNS hijacking while allowing workstations to reside in private subnets. AWS Direct Connect further strengthens security by bypassing the public internet entirely through dedicated fiber connections, reducing exposure to internet-based DDoS attacks, ISP-level surveillance, and routing attacks.
If you have strict compliance requirements, also consider deploying Amazon DCV servers in private subnets with AWS PrivateLink endpoints for fully private connectivity. For comprehensive guidance on these connectivity options and additional firewall and protection services that enhance protection against exploits such as ransomware and DDoS, see Security, Identity and Compliance on AWS (refer back to Part 1’s detailed comparison of connectivity architectures).
AWS Identity and Access Management (IAM)
IAM securely controls access to AWS. With IAM, you can manage authentication and authorization and grant your identities only the least-privilege permissions required for their tasks, reducing the risk of mistakes or unauthorized behavior. Throughout this post series, we’ve applied this principle of least privilege to IAM roles and policies. For example, we attached IAM roles to EC2 instances rather than using long-lived static credentials, eliminating the risk of exposed access keys.
For example, for the purposes of this post, we used read-only policies for S3. For production environments, we recommend taking this further by prescribing:
- Access to specific S3 buckets using resource-level permissions.
- For example,
arn:aws:s3:::amzn-s3-demo-bucket/*.
- For example,
- Limiting actions to only what’s required.
- For example,
s3:GetObjectinstead ofs3:*.
- For example,
Credential security
As a best practice, we recommend changing default passwords immediately and aligning them with your organization’s password quality requirements, such as 16 or more characters with mixed case, numbers, and symbols. Any SSH key pairs should be rotated regularly in line with your organizational requirements.
Monitoring and logging
You can use a number of tools and services to monitor activity within an AWS account. For example, use AWS CloudTrail to audit IAM actions and API calls for compliance and security, and implement Amazon CloudWatch alarms to warn about specific security events. AWS Identity and Access Management Access Analyzer can be used to identify resources shared with external entities and validate that your IAM policies grant only intended access, whilst VPC Flow Logs monitor and allow you to audit network traffic patterns within your network. For vulnerability detection, Amazon Inspector can scan EC2 instances for software and network exposure, whilst Amazon GuardDuty can continuously monitor for threat detection across your infrastructure, looking for suspicious or malicious behavior.
Encryption
Encrypting your data at rest, and in transit helps protect against unauthorized access even if storage media is compromised or network traffic is intercepted. In these posts we made sure that Amazon Elastic Block Store (Amazon EBS) volumes for our instances were all encrypted using AWS Key Management Service (KMS) for encryption key management, providing cryptographic verification and centralized key rotation capabilities. We explored Transport Layer Security (TLS) encryption for Amazon DCV, which helps protect your desktop pixels and user inputs during transmission using TLS v1.2 or greater with strong cipher suites.
Patch management
Consider build-time hardening services such as EC2 Image Builder to automate the creation of Amazon Machine Images (AMIs) that apply the latest security patches, remove unnecessary components, and install anti-malware protection.
For lifecycle management, AWS Systems Manager Patch Manager can automate patching across your fleets. It uses patching policies that scan for and install approved updates on a schedule you define (weekly is recommended). Patch Manager is particularly valuable for fleet-wide VFX workstations because it centralises patching control across multiple accounts and AWS Regions. It supports custom patch baselines, so you can define what counts as compliant for your organisation. It also integrates with AWS Security Hub CSPM (Cloud Security Posture Management) and AWS Config for greater visibility, and it maintains audit trails through AWS CloudTrail.
Backup and recovery
Amazon EBS snapshots represent a cost-effective, encrypted, point-in-time backup of your instance data (such as the operating system and applications) residing on EBS volumes. They’re stored in Amazon Simple Storage Service (Amazon S3). Incremental versions only store the deltas in data from previously stored volumes (deletions of snapshots only remove unique data associated with that volume). With snapshots, you can retrieve a prior state (snapshot) of an instance and resume work or even turn a snapshot into an AMI for more permanent use. Whilst many companies using VFX workstations on AWS tend to regularly launch new daily instances for their artists (avoiding ‘stopped’ state charges overnight and ensuring artists are using up-to-date AMIs), long-term use of Amazon EC2 instances can use EBS snapshots to instigate disaster recovery preparation against accidents, corruption, or ransomware. It’s vital when using disaster recovery processes such as EBS snapshots, that testing is done to confirm that recovery procedures work when needed.
Conclusion
This post has covered essential security practices including network controls, IAM policies, encryption, monitoring, and threat detection, which are all foundational elements of a comprehensive security strategy. For production deployments, we strongly recommend consulting the AWS Security Best Practices documentation and the AWS Well-Architected Framework Security Pillar to explore additional security services, compliance frameworks, and industry-specific guidance tailored to your organization’s requirements.
For more information contact us at [email protected].
About the authors
Building a GPU workstation for visual effects with Amazon EC2: Part 4 – Optimizations
Post Syndicated from Andy Hayes original https://aws.amazon.com/blogs/compute/building-a-gpu-workstation-for-visual-effects-with-amazon-ec2-part-4-optimizations/
For many years, Amazon Web Services (AWS) has been guiding customers in deploying powerful workstations backed by NVIDIA graphics processing units (GPUs) for graphics-intensive workloads. With the recent expansion of our G-series Amazon Elastic Compute Cloud (Amazon EC2) graphics-based instances, we’re excited to introduce new instance families that deliver enhanced performance and capabilities. We’re also refreshing our comprehensive guidance on choosing and configuring these powerful virtual workstations.
This is the fourth post in a five-part series, exploring optimizations to support the ready deployment of visual effects (VFX) workstations, using Amazon DCV as a performant desktop display protocol. The screen capture that follows shows one such workstation running a live visual-effects workload.
“First there were rocks… Humanity made wheels. Those wheels ground flour and we made progress to sliced bread. Amazon DCV is the best thing since sliced bread.”
— Chris Coupe, CG Supervisor, Outpost VFX
Figure 1: A screen capture of a Rocky Linux-based workstation
This post focuses on several key aspects:
- The consolidation and standardization of VFX workstation instance configurations, to allow simpler launching mechanisms, also facilitating deployments at larger scale (for example, a team of people).
- Optimizations to improve performance beyond out-of-the-box setups, with emphasis on GPU acceleration.
- Analysis and discussion of security considerations when implementing a VFX workstation on AWS.
Prerequisites
This post assumes that you have deployed a Linux or Windows EC2 instance, for the purposes of creating a GPU workstation.
If you want to understand more about GPU-accelerated Amazon EC2 G graphics instances, go to Part 1 in this series: Build a GPU workstation for visual effects on Amazon EC2: Part 1 – Setup.
For deployment instructions for creating a Rocky Linux graphics workstation, go to Part 2 in this series: Building a GPU workstation for visual effects on Amazon EC2: Part 2 – Linux.
Finally, for deployment instructions for creating a Windows Server 2025 graphics workstation, go to Part 3 in this series: Building a GPU workstation for visual effects with Amazon EC2: Part 3 – Windows.
Amazon Machine Images and launch templates
You have used existing base Amazon Machine Images (AMIs) as a source for your OS and software, customizing them to your needs. The next step is to produce your own AMIs from these customizations so that you can quickly launch one or more instances from this state in the future. Furthermore, you want to avoid replicating the work that you have just done, while also maintaining a standard environment across the teams that use these instances.
Moreover, when you initiated the workstation instances, you also stipulated the networking, security, permissions, and instance type that define the complete instance alongside the AMI. You can wrap all of this information into an Amazon EC2 launch template to standardize the whole instance, so you can launch it without issues.
Note the current size of the Amazon Elastic Block Store (Amazon EBS) volume that you are using for your OS and applications on your workstation. When you create an AMI you stipulate the size of the volume to associate with it. Keeping the storage size of the AMI efficient makes sure that your (relatively small) storage costs are optimized and any movement and startup using that AMI are as quick as possible.
On Windows, review the size of the C: drive in Windows Explorer by looking at the drive properties, and in a shell in Linux you can use df -h to review filesystem disk space usage.
Preparing a Linux AMI
To prepare Linux, first stop the instance, if it is running:
- In the Amazon EC2 console, choose Amazon EC2 Dashboard in the top left.
- Choose Instances (running).
- Choose the
my_linux_workstationinstance in the top pane. - Open the context menu for the instance, and choose Stop instance.
- Wait for the Instance state to move from Running to Stopped.
Preparing a Windows AMI
Windows Server 2025 uses the agent EC2Launchv2 on bootup to perform system tasks. You must configure the agent before shutting down the instance, prior to making an AMI, through the Amazon EC2LaunchSettings application. The following screen capture shows the EC2Launch Settings application, where you set the boot-time behavior of the agent. In this example, the General tab is open. This tab controls launch-time options for the instance, such as setting the instance name and configuring the administrator username and password.
Figure 2: A screen capture of the Amazon EC2Launch Settings application, used to configure the EC2Launch agent on bootup
On your Windows instance, open the Amazon EC2Launch settings application.
This application controls which tasks the agent performs on boot. Pertinent options to enable are as follows:
Host name:
- Turn on “Set the compute name of the instance”, and set it to
ip-<hex primary IP address>. - Turn on “Reboot after setting Computer Name”.
This makes sure that the compute host name is unique upon booting for future considerations toward Active Directory, render farms, and so on.
Password
- Turn on Set the administrator account.
- Set the Administrator username (for example, Administrator).
- Specify the Administrator password.
This can be the same as what you previously set before, or you can change it.
Wallpaper (on the third tab)
You can specify the custom Windows wallpaper and stat burn-in of various instance parameters.
- When you have made your changes, choose Save at the bottom of the screen to save your configuration changes.
You have two choices to shut down based on Sysprep.
Shut down without Sysprep
This option is useful if you have embedded information on the image that you want to retain (for example, local users for processes) that would otherwise be removed by Sysprep.
Shut down with Sysprep
For removing PC-specific information for future AMI consideration:
- Shut down with Sysprep on this occasion. The machine automatically shuts down.
Wait for the Instance state to move from Running to Stopped.
You can find more information about Amazon EC2 Launch in the Amazon EC2 User Guide.
Creating the AMI
When your instances are in the Stopped state, you can proceed with making your AMI.
- In the Amazon EC2 console, choose Instances in the top left.
- Choose your workstation instance by selecting the checkbox next to its name.
- Choose Actions from the top right of the pane, and choose Image and templates, Create image.
In the Create image page, specify the options for your AMI:
- Give your AMI an Image name. You might want to consider versions in the AMI name.
- For example,
VFX_Workstation_Linux_v001.
- For example,
- Give your AMI a relevant Image description.
- For example,
base build, with GPU, WACOM, CLI.
- For example,
- The Size of your storage can be specified. As mentioned previously, consider reducing this down to something that is more aligned with your actual usage, such as usage + 20 percent.
- Consider adding a new tag to give your AMI a discernible name.
- For example, add a Name tag key, and paste the Image name as the value.
- Choose Create image to make the AMI. This can take several minutes to complete.
Amazon EC2 AMIs can be shared across accounts and Regions, which lets teams standardize workstation configurations and deploy them quickly. Because a VFX workstation AMI often bakes in licensed digital content creation (DCC) tools, render plugins, studio tooling, and credentials, treat it as a controlled asset rather than something to share broadly.
Share each AMI only with the specific accounts that need it and prefer sharing with named AWS account IDs over making an AMI public. Before you share, confirm the image contains no embedded secrets such as application API keys, license tokens, or SSH keys baked in during the build. Audit your sharing configuration periodically so access does not outlive its purpose and revoke it when a team or project no longer needs the image.
Creating a launch template
When you launched the EC2 instance, as well as the AMI to use, you also stipulated other options that were important to define how the machine launched, such as the network, security groups, and roles. Rather than do this each time that you want to start an instance, you can combine all this information, and more, into an Amazon EC2 launch template. You can then quickly launch machines in the future, or combine them with other brokering and scaling mechanisms to control larger usage of the machines. This is useful for studios with multiple artists, or render farms with multiple machines, all using standardized environments.
You can build a launch template through the Amazon EC2 console:
- In the Amazon EC2 console, choose Launch Templates under the Instances section on the left.
- Choose Create launch template on the right side of the pane.
- Provide a Launch template name and description in the relevant boxes.
Launch templates are versioned, so there is no need to add a version number to its name.
- For the AMI, choose My AMIs and choose the relevant AMI that you made in the previous steps.
- Under Instance type choose g6.4xlarge. This is the default size for your template (but this and all values can be overridden at launch time if you wish).
- Provide your
ec2_test_keypairin the Key pair (login). - Edit the Network settings to adjust security and network placement:
- Leave the Subnet to Don’t include in launch template.
- Under the Firewall (security groups) section of the Network Settings, choose Select existing security group, and choose the “ec2_test_sg” that you made earlier to set up the firewall for the machine.
- In Resource tags, add a Name key tag, with a value of
my_workstationor another suitable name. - Under Advanced details, specify the
basic_workstation_rolethat you made previously through the IAM instance profile list, to allow your workstation to access more services.
There are many other options that you can explore in launch templates. A useful feature is found at the bottom of the Advanced details: the User data. With user data, you can enter Windows PowerShell or Linux shell commands to run on boot, adding configurations or modifications on top of the AMI. This circumvents the need to publish new AMIs for certain kinds of change. An example of this can be found in the following GPU performance optimization section, but for now you can finish making the launch template.
- Choose Create launch template.
When you return to the Launch templates dashboard, your newly created template appears in the list. Select the template, then choose Launch instance from template from the Actions menu to open a dialog for launching a new instance from it. The dialog shows the template’s values and lets you adjust any setting before launch. You can also modify a template to create new versions and set a default version. This way, you can keep multiple versions for comparison while clearly marking which one to use by default. The following screen capture shows the dialog, where you confirm the source template and version and optionally override its settings before launching.
Figure 3: The Amazon EC2 launch template UI can be used to quickly start an instance, with options to override existing parameters
Launch templates can be used in other services to streamline and control instance starting mechanisms at scale, such as Amazon EC2 Auto Scaling groups, as well as third-party services listed in the Further reading section.
This post demonstrates how to build an AMI in manual steps. There are alternate services to create an AMI that can cater to larger scaling mechanisms to support productions. For example, Amazon EC2 Image Builder allows you to define recipes and schedules for automating the creation of AMIs.
GPU performance optimization
There’s dedicated AWS documentation in the Amazon EC2 User Guide regarding GPU optimizations. This includes initializing the persistent driver kernel on Linux, to keep GPU states initialized regardless of client connections:
It also includes documenting how to turn off GPU autoboost, for slightly more efficient GPU usage. This option should be considered and evaluated on a per-application basis to ascertain positive or negative impact on performance. Go to the preceding documentation for more information.
Outside of the official documentation on AWS, for VFX-specific workloads a further optimization can be made regarding NVIDIA Error Correction Code (ECC). Amazon EC2 G instance family types use NVIDIA data center cards, designed for high performance computing. These differ from the consumer-style cards typically found in individual workstations in offices. On data center cards, ECC is provisioned and enabled as a method to introspectively look for potential pixel errors because of bit flipping through phenomena such as cosmic ray interaction, and fix any errors found.
You should consider deactivating this feature to reduce the overhead of memory checking on the GPU, to gain performance. ECC isn’t typically available on consumer GPU cards, so many customers’ workloads haven’t relied on this error-correction feature in the first place. If debugging requires it, the feature can be quickly re-enabled.
ECC is activated on every fresh start of an EC2 instance, and disabling necessitates a reboot. You can automate turning it off with a traditional startup script, or with the previously mentioned User data script as part of the launch template.
For a Windows instance, you can add the User data script by inserting it between leading and trailing powershell elements to define a PowerShell script, with the persist element added so the script runs again on each reboot cycle, and not only on the first boot.
For a Linux instance, you can enter a shell script:
User data is a mechanism to make changes to EC2 instances, without reverting to changing the underlying AMI. However, you should avoid hardcoding and storing sensitive data in it, that might pose a visible compliance or security risk. AWS Secrets Manager can be used to obfuscate sensitive data, as it stores and manages the lifecycle of secrets, and provides robust mechanisms to pass that data programmatically into process within a user data context.
Cleaning up
Remember to turn off your instances when not in use. You can turn them off either through the AWS Management Console, or through other programmatic methods such as the AWS Command Line Interface (AWS CLI). You incur costs associated with a running machine, so deactivating machines when not in use reduces your expenditure.
There are two different options for deactivating an EC2 instance: stopping and terminating.
Stopping
When you stop an instance, its Amazon EBS volumes remain attached and their data is retained, so your work on the EBS volume persists while the instance is deactivated. Data held in memory (RAM) is not preserved, and neither is any data on the instance store (NVMe) volumes (that data is lost when the instance stops).
You perform this operation by choosing the instance from the Amazon EC2 console, and under the Instance state options you can elect to Stop instance. The instance remains in your console, with a “Stopped” state, but the persistent volumes enable you to restart the instance and resume your session when you want, retaining any changes that you made to the main volume. You can restart an instance by using the Start instance operation under the Instance state options.
When an instance is “Stopped”, you don’t pay for the instance itself but incur a smaller charge for the storage of the volume.
Terminating
This operation deactivates the instance and does not retain any information locally stored. You can’t restart a terminated instance.
To terminate an instance, choose Terminate instance from the Instance state options on the Amazon EC2 console. The instance shuts down and reports a “Terminated” state on the console, and automatically disappears after a short time.
For more information about Amazon EC2 lifecycles, options, and billing, go to the Amazon EC2 User Guide.
Conclusion
This post has demonstrated how existing base AMIs can be used as a source for creating a custom VFX workstation, with further GPU optimizations applied to increase performance. These customizations can be published as new AMIs themselves for quick redeployment of that machine setup. Then, you integrated this AMI into a launch template to specify the complete array of startup requirements needed for a workstation, for quick and standardized deployment of machines.
We recommend that you continue to the final Part 5 of our series, Building a GPU workstation for visual effects with Amazon EC2: Part 5 – Security, to explore security practices related to the deployment of visual effects (VFX) workstations. This post examines how to secure these workstations by controlling who can reach the desktop, protecting the session in transit, and safeguarding the credentials, images, and storage behind it.
For more information, contact us at [email protected].
Further reading
If you want to augment a VFX workstation environment with a dedicated render farm, then consider the managed service AWS Deadline Cloud.
EC2 instance metrics, such as CPU and memory usage, are readily sent to Amazon CloudWatch logs, allowing you to access this data through the console and AWS CLI. This information can be pertinent to discern if an EC2 instance is being over-provisioned or under-provisioned for the work at hand. For example, it has excessive CPU, memory, and networking resources for the current tasks and could be optimized for price, or the alternative where it has not been allocated enough resources to cope. For more information, visit the Amazon EC2 User Guide.
Windows instances can be lengthy to boot. Amazon EC2 Fast Launch for Windows is an AWS facility for quicker launching of Windows machines through smart snapshots of the AMI.
The following post shows how to programmatically configure a Windows EC2 instance as part of a domain. This is particularly useful when the instances are used ephemerally, for example as part of a fleet of instances that spool up and down for the purposes of rendering, and you need methods to bind and remove instances quickly.
Commercial options also exist to perform artist/instance brokering, using Amazon DCV and Amazon EC2 launch templates. An example of this offering is Leostream.
About the authors
Building a GPU workstation for visual effects with Amazon EC2: Part 3 – Windows
Post Syndicated from Andy Hayes original https://aws.amazon.com/blogs/compute/building-a-gpu-workstation-for-visual-effects-with-amazon-ec2-part-3-windows/
For many years Amazon Web Services (AWS) has been guiding customers in the deployment of powerful NVIDIA GPU-backed workstations for graphics-intensive workloads. With the recent expansion of our G-series Amazon Elastic Compute Cloud (Amazon EC2) graphics-based instances, we are excited to introduce new instance families that deliver enhanced performance and capabilities. We are also refreshing our comprehensive guidance on choosing and configuring these powerful virtual workstations.
This is the third post in a five-part series, focusing on the deployment of a Windows Server 2025 visual effects (VFX) workstation, using Amazon DCV as a performant desktop display protocol.
“Amazon DCV has unlocked previously unrealised playback performance, that has massively increased my productivity. Amazon DCV is performant on a range of systems and where other solutions have failed, I have been able to continue working and most importantly, continue delivering”
— Chris Coupe, CG Supervisor, Outpost VFX
Prerequisites
This post assumes that you have configured the following:
- An active AWS account with increased GPU Amazon EC2 service quota limits.
- A valid key pair in your AWS Region of choice.
- A configured virtual firewall security group, with open TCP/UDP ports 22, 443, 8443, and 3389 limited to only your own IP address.
- An AWS Identity and Access Management (IAM) profile with least-permissions Amazon Simple Storage Service (Amazon S3) read access.
We strongly recommend that you follow Part 1 of the series, Build a GPU workstation for visual effects on Amazon EC2: Part 1 – Setup, which goes through the preceding steps in detail.
Launching the Windows workstation
We use the latest AWS provided Windows Server 2025 Amazon Machine Image (AMI) for our deployment, and install the NVIDIA, Amazon DCV, and Wacom components to create a fully functioning VFX Windows desktop environment.
Follow these steps to launch a g6.4xlarge instance in your chosen AWS Region. If you want to use multiple GPU cards (for example, by using the 12xlarge, 24xlarge, or 48xlarge instance types), then Windows requires you to have that number of GPU cards present when setting up the GPU driver. In this case, we recommend starting the relevant multiple GPU instance size when making your AMI.
- Log in to the AWS Management Console and choose EC2 Dashboard in the top left.
- Choose Launch instances to start the prompt to launch a new instance.
- Give the instance a name, for example
my_windows_workstation. - Choose Windows under the Quick Start AMI and use the default Microsoft Windows Server Base Image 2025.
- Under Instance type, choose g6.4xlarge.
- Under Key pair name, choose the menu and choose your key pair. In the previous post we called it
ec2_test_keypairto specify the password security credentials. - Edit the Network settings to adjust security and network placement:
- Leave the Subnet to No preference.
- Make sure that Auto-assign public IP is set to Enable, so that you can access the instance through the internet.
- Under the Firewall (security groups) section of the Network Settings, choose Select existing security group, and specify your security group. In the previous post we named it
ec2_test_sgto set up the firewall for the machine. - In Configuration storage, expand the default root volume from 10 GiB to 50 GiB of gp3 storage.Important: Turn on encryption in the Advanced options by selecting the Encrypted option and selecting the default AWS managed key (aws/ebs) or a customer-managed KMS key for enhanced control. Amazon Elastic Block Store (Amazon EBS) encryption protects your VFX project files, renders, and application data at rest. Encryption uses industry-standard AES-256 encryption and is transparent to applications with minimal performance impact.
- Under Advanced details, specify the role that you created for workstation usage. In the previous post we called it
basic_workstation_rolethrough the IAM instance profile menu, so your workstation can access more services. - Choose Launch instance on the right-hand side, as shown in the following figure.
Choose the link to the EC2 instance that has been launched, or view it through the Instances pane in the Amazon EC2 Service page. The following screen capture shows the newly launched workstation in the EC2 Instances list, where you can confirm it is ready to use. Wait until the my_windows_workstation instance shows an Instance state of Running and a Status check of 3/3 checks passed. Once both conditions are met, you can continue.
Figure 1: A screen capture of the EC2 Instances page, showing the my_windows_workstation in a ready state
Configuring the Windows workstation
In the last part of our series, Building a GPU workstation for visual effects with Amazon EC2: Part 4 – Optimizations, we show how to add scripting capabilities to the boot sequence of EC2 instances. This runs processes such as the NVIDIA GPU driver and Wacom tablet driver automatically during the startup of a machine. For the purposes of this post, we take a more manual approach, showing how you can remote into the machine to perform setup tasks.
You initially connect to the instance through the Windows Remote Desktop Protocol (RDP). In the Amazon EC2 Service page browser tab with the list of EC2 instances running, again choose the my_windows_workstation and choose Connect.
Choose the RDP client tab to connect to the machine through RDP with the following steps:
- Choose the Get password option to retrieve the Administrator password for the machine through your key pair credential.
- Upload the private
ec2_test_keypair.pem key file that you downloaded previously and choose Decrypt password. - The password is now displayed. Copy the password into the clipboard memory by choosing the copy icon, and choose OK, as shown in the following figure.
Figure 2: A screen capture of the Get Windows Password retrieval options available to EC2 instances
- Choose Download remote desktop file to download the .rdp file to your local machine.
- Run the .rdp file with your Remote Desktop Application of choice.
- When prompted, paste the previously copied
Administratorpassword and choose OK. - Choose Yes to trust the machine, and the session is authenticated and opened.
Security
We recommend setting a new, private password when you first start the fresh instance.
Open a Windows PowerShell to configure and make changes to the workstation. In the shell, configure that change and store your new password in a safe place.
Tools
To install the AWS Command Line Interface (AWS CLI) enter the following into the shell, and follow the on-screen prompts:
Graphics
You must use AWS approved NVIDIA GPU drivers, issued through Amazon S3, not only for optimal compatibility and performance, but also to make sure that the necessary professional GRID drivers are automatically provisioned. You can always find the latest instructions in the Amazon EC2 Windows User Guide. At the time of writing, you can download the latest version to your desktop by running the following in a new Windows PowerShell:
When it is downloaded, navigate to your Desktop, open the NVIDIA folder, then the latest folder inside, and run the NVIDIA installer executable, following the instructions.
Wacom support and Wacom Bridge
To add Wacom stylus support on the workstation, open Microsoft Edge (or install your browser of choice) and download and install the latest drivers from the Wacom drivers page.
Wacom Bridge is now generally available on Windows and Mac, and offers new advantages for Wacom users on AWS:
- Applications running locally and remotely on AWS transfer their Wacom-specific settings automatically.
- Artists can switch from local to remote use of the pen by choosing the necessary application window.
- Wacom Inkline draws an instant temporary line on your screen, to bridge any gap between the local pen tip and the remote drawn line.
- Amazon DCV provides enhanced security through data transport encrypted through HTTPS/TLS connections.
You can purchase a Wacom Bridge license (or request a trial) from a Wacom Sales representative.
Amazon DCV setup
To use Amazon DCV, you need to download the server application for the Amazon EC2 workstation from https://www.amazondcv.com/.
On the Amazon EC2 workstation, open the preceding link in your browser of choice, expand the latest Amazon DCV Server entry (2026.0 at the time of this post), choose the Windows (x86_64) link, download the installer, and run it. The default options automatically configure firewall entries for the Amazon DCV server ports, and start the Amazon DCV server.
Instance store setup
Finally, consider setting up the instance store on the instance:
- In the search bar at the bottom of the screen, enter
Computer Managementand press Enter. - Choose Disk Management in the left pane.
- If prompted, then choose OK to accept the requested formatting of the instance store. The following figure shows such a prompt.
- Open the context menu for the Unallocated drive and choose New Simple Volume.
- Accept the requests, making any wanted changes to the drive name, or assigning to a folder instead.
- Choose Finish and the new volume is available to use as a temporary drive.
Figure 3: The Disk Management tool prompting the automatic formatting of the instance store
Proceed to the next section to log in to your workstation to use Amazon DCV.
Logging into your workstation through Amazon DCV
To log in to your machine using Amazon DCV, you must first set up the client software on your local machine:
- On your local machine or laptop, open Amazon DCV.
- Expand the Amazon DCV Client entry that matches the Server version that you installed on your workstation.
- Choose the relevant OS for your machine or laptop, for example Windows (x86_64).
- Download the installer.
- Run the installer.
When it is installed, you must determine the public IP address of the workstation to connect to:
- In the Amazon EC2 Console, choose Amazon EC2 Dashboard in the top left.
- Choose Instances (running).
- Choose the
my_windows_workstationEC2 instance, in the top pane of the screen. - Choose the copy icon next to the Public IPv4 address in the lower pane to copy the IP address.
Finally, use the Amazon DCV client to view the workstation:
- Open the Amazon DCV client on your local machine.
- Paste the previous IP address and press Enter, then trust the connection.
- You will see a security warning about an untrusted certificate. This is expected behavior because Amazon DCV uses a self-signed certificate by default. For this initial setup, it is safe to accept the certificate and proceed with the connection. For a detailed explanation of why this warning appears and how to implement proper certificate security for production environments, see Amazon DCV Connection Security in Building a GPU workstation for visual effects with Amazon EC2: Part 5 – Security.
- In the next Username / Password entry field, choose Administrator, and the appropriate password to which you set that user.
After the connection is established, Amazon DCV opens and displays the remote workstation desktop. The following screen capture shows the running workstation, confirming that your remote session is active and the environment is ready to use. In this example, the Windows Server 2025 desktop is shown with SideFX Houdini open, displaying a rendered scene in the viewport above the Windows taskbar.
Figure 4: A screen capture of a Windows Server 2025 based workstation
With Windows, you automatically get brush sensitivity with Wacom and Amazon DCV connectivity. You don’t need to configure additional steps for your brushes to dynamically use the tablet’s controls.
Note: If you have need for a managed, non-persistent Windows desktop where several users share one GPU instance, consider Amazon WorkSpaces Applications multi-session fleets. They’re best for lighter graphics users such as reviewers, CAD viewers and editors, rather than artists working heavily in the viewport.
Cleaning up
Finally, you must remember to turn off your instances when not in use, either through the AWS Management Console, or through other programmatic methods such as AWS CLI. You incur costs associated with a running machine, and so deactivating machines when not in use reduces your expenditure.
This can be done by choosing Terminate instance from the Instance state options of the workstation in the Amazon EC2 console. The instance shuts down and reports a Terminated state on the console, but it automatically disappears after a short time.
However, if you want to learn more about the various methods to deactivate an EC2 instance, and create a persistent machine image of your Windows instance, then refer to Part 4 of the series, Building a GPU workstation for visual effects with Amazon EC2: Part 4 – Optimizations.
Conclusion
This post has shown how Amazon EC2 instances running Windows Server 2025 can create a GPU-backed VFX workstation. Your artists can use the latest technologies to unlock efficiencies, unhampered by the lengthy hardware renewal cycles typically found in on-premises environments.
We recommend that you continue to Part 4 of our series, Building a GPU workstation for visual effects with Amazon EC2: Part 4 – Optimizations, to learn how to implement GPU optimizations and infrastructure to streamline the provisioning of workstations. Part 4 also covers essential information on security practices for Windows EC2 instances, including build-time hardening and automated patch management to protect your workstation infrastructure from evolving threats.
For more information, contact us at [email protected].
Further reading
If you want to augment a VFX workstation environment with a dedicated render farm, then consider the managed service AWS Deadline Cloud.
EC2 instance metrics, such as CPU and memory usage, are sent to Amazon CloudWatch logs, so you can access this data through the console and AWS CLI. This information helps you discern whether an EC2 instance is over- or under-provisioned for the work at hand. For example, an instance might have excessive CPU, memory, and networking resources for the current tasks and could be optimized for price. Alternatively, it might not have enough resources to cope. For more information, visit the Amazon EC2 User Guide.
Windows instances can be lengthy to boot. Amazon EC2 Fast Launch for Windows is an AWS feature for faster launching of Windows machines through smart snapshots of the AMI.
Another post shows how to programmatically configure a Windows EC2 instance as part of a domain. This is particularly useful when the instances are used ephemerally, for example as part of a fleet of instances that spool up and down for rendering, and you need methods to bind and remove instances quickly.
More advanced examples of using Amazon DCV can be found in the aws-samples dcv-samples GitHub repo. This includes methods to broker multiple users and instances. Amazon DCV Connection Gateway provides a single entry point for users to connect to multiple Amazon DCV sessions across different instances, streamlining access management and improving security through centralized authentication.
Commercial options also exist to perform artist/instance brokering, using Amazon DCV and Amazon EC2 launch templates. An example of such an offering is Leostream.
For reference, examples of setting up Amazon DCV-capable instances and using AWS CloudFormation templates as a deployment method can be found in the amazon-ec2-nice-dcv-samples GitHub repo.
A deeper analysis of bit rates and latency for Amazon DCV connections can be found in this AWS HPC Blog post.
More information about Wacom Bridge running on Amazon DCV can be found in this AWS Wacom post and re:Invent 2024 talk.