Application Security Posture Management

Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/01/16/application-security-posture-management/
Application Security Posture Management

Accelerating the Remediation of Vulnerabilities From Code To Cloud

Written by Eric Sheridan, Chief Innovation Officer, Tromzo

In this guest blog post by Eric Sheridan, Chief Innovation Officer at valued Rapid7 partner Tromzo, you’ll learn how Rapid7 customers can utilize ASPM solutions to accelerate triaging, prioritization and remediation of findings from security testing products such as InsightAppSec and InsightCloudSec.

Application Security’s Massive Data Problem

Application Security teams have a massive data problem. With the widespread adoption of cloud native architectures and increasing fragmentation of development technologies, many teams amass a wide variety of specialized security scanning tools. These technologies are highly specialized, designed to carry out comprehensive security testing as a means of identifying as many vulnerabilities as possible.

A natural byproduct of their deployment at scale is that, in aggregate, application security (appsec) teams are presented with thousands – if not millions – of vulnerabilities to process. If you’re going to deploy advanced application security testing solutions, then of course a significant amount of vulnerability data is going to be generated. In fact, I’d argue this is a good problem to have. It’s like the old saying goes: You cannot improve what you cannot measure.

Here’s the kicker though: given a backlog of, lets say 200k vulnerabilities with a severity of “critical” across the entire product stack, where do you start your remediation efforts and why? Put another way: is this critical more important than that critical? Answering this question requires additional context, of which is often manually obtained by appsec teams. And how do you then disseminate that siloed vulnerability and track its remediation workflow to resolution? And can you replicate that for the other 199,999 critical vulnerabilities? This is what I mean when I say appsec teams have a massive data problem. Accelerating remediation, reducing risk, and demonstrating ROI requires us to be able to act on the data we collect at scale.

Introducing Application Security Posture Management

Overcoming Application Security’s massive data problem requires a completely new approach to how we operationalize vulnerability remediation, and this is exactly what Application Security Posture Management (ASPM) is designed to solve. In a recent Innovation Insight, Gartner defined ASPM as follows:

“Application security posture management analyzes security signals across software development, deployment and operation to improve visibility, better manage vulnerabilities and enforce controls. Security leaders can use ASPM to improve application security efficacy and better manage risk.” – Gartner

Obtaining and analyzing “security signals” requires integrations with various third party technologies as a means of deriving the context necessary to better understand the security implications of vulnerabilities within your enterprise and its environment. To see this in action, let’s revisit the question: “Is this critical more important than that critical?” A robust ASPM solution will provide you context beyond just the vulnerability severity as reported by the security tool. Is this vulnerability associated with an asset that is actually deployed to production? Is the vulnerability internet-facing or internal only? Does either of these vulnerable assets process sensitive data, such as personally identifiable information (PII) or credit card information? By integrating with third party services such as Source Code Management systems and Cloud runtime environments, for example, ASPM is able to enrich vulnerabilities so that appsec teams can make more informed decisions about risk. In fact, with this additional context, an ASPM helps Application Security teams identify those vulnerabilities representing the greatest risk to the organization.

Identifying the most significant vulnerabilities is only the first step, however. The second step is automating the remediation workflow for those vulnerabilities. ASPM enables the scalable dissemination of security vulnerabilities to their respective owners via integration with the ticketing and work management systems already in use by your developers today. Better yet, Application Security teams can monitor the remediation workflow of vulnerabilities to resolution all from within the ASPM. From a collaboration perspective, this is a massive win-win: development teams and appsec teams are able to collaborate on vulnerability remediation using their own respective technologies.

When you put all of this together, you’ll come to understand the greatest value-add provided by ASPM and realized by our customers at Tromzo:

ASPM solutions accelerate the triage and remediation of vulnerabilities representing the greatest risk to the organization at scale.

ASPM Core Capabilities

Effectively delivering on an integrated experience that accelerates the triage and remediation of vulnerabilities representing the greatest risk requires several core capabilities:

  1. The ability to aggregate security vulnerabilities across all scanning tools without impeding your ability to use the best-in-class security testing solutions.
  2. The ability to integrate with and build context from development tools across the CI/CD pipeline.
  3. The ability to derive relationships between the various software assets and security findings from code to cloud.
  4. The ability to express and overlay organizational- as well as team-specific security policies on top of security vulnerabilities.
  5. The ability to derive actions and insights from this metadata that help prioritize and drive to remediation the most significant vulnerabilities.

Doing this effectively requires a tremendous amount of data, connectivity, analysis, and insight. With integrations across 70+ tools, Tromzo is delivering a best-in-class remediation ASPM solution.

How Rapid7 Customers Benefit from an ASPM Solution

By its very nature, ASPM fulfills the need for automation and efficiency of vulnerability remediation via integration across various security testing solutions and development technologies. With efficiency comes real cost savings. Let’s take a look at how Rapid7 customers can realize operational efficiencies using Tromzo.

Breaking Down Security Solution Silos

Rapid7 customers are already amassing best-in-class security testing solutions, such as InsightAppSec and InsightCloudSec. ASPM enables the integration of not only Rapid7 products but all your other security testing products into a single holistic view, whether it be Software Composition Analysis (SCA), Static Application Security Testing (SAST), Secrets Scanning, etc. This effectively breaks down the silos and operational overhead with individually managing these stand-alone tools. You’re freeing yourself from the need to analyze, triage, and prioritize data from dozens of different security products with different severity taxonomies and different vulnerability models. Instead, it’s: one location, one severity taxonomy, and one data model. This is a clear win for operational efficiency.

Accelerating Vulnerability Remediation Through Deep Environmental and Organizational Context

Typical security teams are dealing with hundreds of thousands of security findings and this takes us back to our question of “Is this critical more important than that critical?”. Rapid7 customers can leverage Application Security Posture Management solutions to derive additional context in a way that allows them to more efficiently triage and remediate vulnerabilities produced by best-of-breed technologies such as InsightAppSec and InsightCloudSec. By way of example, let’s explore how ASPM can be used to answer some common questions raised by appsec teams:

1. Who is the “owner” of this vulnerability?

Security teams spend countless hours trying to identify who introduced a vulnerability so they can identify who needs to fix it. ASPM solutions are able to help identify vulnerability owners via the integration with third party systems such as Source Code Management repositories. This automated attribution serves as a foundation to drive remediation by teams and individuals that own the risk.

No more wasted hours!

2. Which vulnerabilities are actually deployed to our production environment?

One of the most common questions that arises when triaging a vulnerability is whether it is deployed to production. This often leads to additional questions such as whether it is internet-facing, how frequently the asset is being consumed, whether the vulnerability has a known exploit, etc. Obtaining answers to these questions is tedious to say the least.

The “code to cloud” visibility offered by ASPM solutions allows appsecteams to quickly answer these questions. By way of example, consider a CVE vulnerability found within a container hosted in a private registry. The code-to-cloud story would look something like this:

  • A developer wrote a “Dockerfile” or “Containerfile” and stored it in GitHub
  • GitHub Actions built a Container from this file and deployed it to AWS ECR
  • AWS ECS pulled this Container from ECR and deployed it to Production

With an integration into GitHub, AWS ECR, and AWS ECS, we can confidently conclude whether or not the Container hosted in AWS ECR is actually deployed to production via AWS ECS. We can even take this further: By integrating within GitHub, we can even map the container back to the corresponding Dockerfile/Containerfile and the team of developers that maintain it.

No more laborious meetings!

3. Does this application process PII or credit card numbers?

Appsecteams have the responsibility of helping their organization achieve compliance with various regulations and industry standards, including GDPR, CCPA, HIPAA, and PCI DSS. These standards place emphasis on the types of data being processed by applications, and hence appsec teams can understand what applications process what types of sensitive data. Unfortunately, obtaining this visibility requires security teams to create, distribute, collect, and maintain questionnaires that recipients often fail to complete.

ASPM solutions have the ability to derive context around the consumption of sensitive data and use this information to enrich applicable security vulnerabilities. A vulnerability deployed to production that stands to disclose credit card numbers, for example, will likely be treated with the highest of priority as a means of avoiding possible fines and other consequences associated with PCI DSS.

No more tedious questionnaires!

4. How do I automate ticket creation for vulnerabilities?

Once you know what needs to be fixed and who needs to fix it, the task of remediating the issue needs to be handed off to the individual or team that can implement a fix. This could involve taking hundreds or thousands of vulnerabilities, de-duplicating them, and grouping them into actionable tasks while automating creation of tickets in a format that is consumable by the receiving team. This is a complex workflow that not only involves automating correctly formatted tickets with the right level of remediation information, but also tracking the entire lifecycle of that ticket until remediation, followed by reporting of KPIs. ASPM solutions like Tromzo are perfectly suited to automate these ticketing and governance workflows, since ASPMs already centralize all vulnerabilities and have the appropriate contextual and ownership metadata.

Leverage ASPM to Accelerate Vulnerability Remediation

ASPM solutions enable Rapid7 customers to accelerate the remediation of vulnerabilities found by their preferred security testing technologies. With today’s complex hybrid work environments, the increased innovation and sophistication of attackers, and the underlying volatile market, automated code to cloud visibility and governance is an absolute must for maximizing operational efficiency and Tromzo is here to help. Check out www.tromzo.com for more information.

Security updates for Tuesday

Post Syndicated from corbet original https://lwn.net/Articles/958416/

Security updates have been issued by Gentoo (KTextEditor, libspf2, libuv, and Nettle), Mageia (hplip), Oracle (container-tools:4.0, gnutls, idm:DL1, squid, squid34, and virt:ol, virt-devel:rhel), Red Hat (.NET 6.0, krb5, python3, rsync, and sqlite), SUSE (chromium, perl-Spreadsheet-ParseXLSX, postgresql, postgresql15, postgresql16, and rubygem-actionpack-5_1), and Ubuntu (binutils, libspf2, libssh2, mysql-5.7, w3m, webkit2gtk, and xerces-c).

Using generative infrastructure as code with Application Composer

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/using-generative-infrastructure-as-code-with-application-composer/

This post is written by Anna Spysz, Frontend Engineer, AWS Application Composer

AWS Application Composer launched in the AWS Management Console one year ago, and has now expanded to the VS Code IDE as part of the AWS Toolkit. This includes access to a generative AI partner that helps you write infrastructure as code (IaC) for all 1100+ AWS CloudFormation resources that Application Composer now supports.

Overview

Application Composer lets you create IaC templates by dragging and dropping cards on a virtual canvas. These represent CloudFormation resources, which you can wire together to create permissions and references. With support for all 1100+ resources that CloudFormation allows, you can now build with everything from AWS Amplify to AWS X-Ray.

­­Previously, standard CloudFormation resources came only with a basic configuration. Adding an Amplify App resource resulted in the following configuration by default:

  MyAmplifyApp:
    Type: AWS::Amplify::App
    Properties:
      Name: <String>

And in the console:

AWS App Composer in the console

AWS App Composer in the console

Now, Application Composer in the IDE uses generative AI to generate resource-specific configurations with safeguards such as validation against the CloudFormation schema to ensure valid values.

When working on a CloudFormation or AWS Serverless Application Model (AWS SAM) template in VS Code, you can sign in with your Builder ID and generate multiple suggested configurations in Application Composer. Here is an example of an AI generated configuration for the AWS::Amplify::App type:

AI generated configuration for the Amplify App type

AI generated configuration for the Amplify App type

These suggestions are specific to the resource type, and are safeguarded by a check against the CloudFormation schema to ensure valid values or helpful placeholders. You can then select, use, and modify the suggestions to fit your needs.

You now know how to generate a basic example with one resource, but let’s look at building a full application with the help of AI-generated suggestions. This example recreates a serverless application from a Serverless Land tutorial, “Use GenAI capabilities to build a chatbot,” using Application Composer and generative AI-powered code suggestions.

Getting started with the AWS Toolkit in VS Code

If you don’t yet have the AWS Toolkit extension, you can find it under the Extensions tab in VS Code. Install or update it to at least version 2.1.0, so that the screen shows Amazon Q and Application Composer:

Amazon Q and Application Composer

Amazon Q and Application Composer

Next, to enable gen AI-powered code suggestions, you must enable Amazon CodeWhisperer using your Builder ID. The easiest way is to open Amazon Q chat, and select Authenticate. On the next screen, select the Builder ID option, then sign in with your Builder ID.

Enable Amazon CodeWhisperer using your Builder ID

Enable Amazon CodeWhisperer using your Builder ID

After sign-in, your connection appears in the VS Code toolkit panel:

Connection in VS Code toolkit panel

Connection in VS Code toolkit panel

Building with Application Composer

With the toolkit installed and connected with your Builder ID, you are ready to start building.

  1. In a new workspace, create a folder for the application and a blank template.yaml file.
  2. Open this file and initiate Application Composer by choosing the icon in the top right.
Initiate Application Composer

Original architecture diagram

The original tutorial includes this architecture diagram:

Original architecture diagram

Initiate Application Composer

First, add the services in the diagram to sketch out the application architecture, which simultaneously creates a deployable CloudFormation template:

  1. From the Enhanced components list, drag in a Lambda function and a Lambda layer.
  2. Double-click the Function resource to edit its properties. Rename the Lambda function’s Logical ID to LexGenAIBotLambda.
  3. Change the Source path to src/LexGenAIBotLambda, and the runtime to Python.
  4. Change the handler value to TextGeneration.lambda_handler, and choose Save.
  5. Double-click the Layer resource to edit its properties. Rename the layer Boto3Layer and change its build method to Python. Change its Source path to src/Boto3PillowPyshorteners.zip.
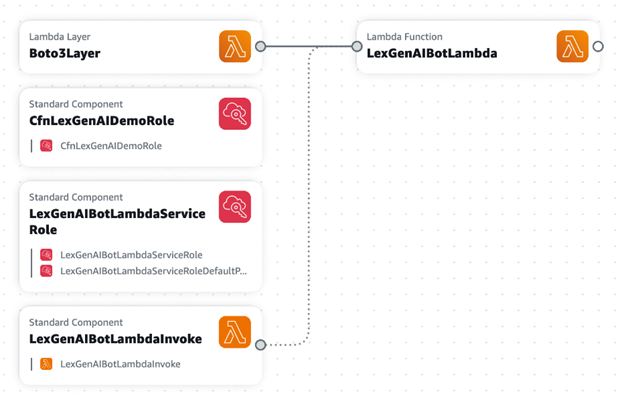
  6. Finally, connect the layer to the function to add a reference between them. Your canvas looks like this:
Your App Composer canvas

Your App Composer canvas

The template.yaml file is now updated to include those resources. In the source directory, you can see some generated function files. You will replace them with the tutorial function and layers later.

In the first step, you added some resources and Application Composer generated IaC that includes best practices defaults. Next, you will use standard CloudFormation components.

Using AI for standard components

Start by using the search bar to search for and add several of the Standard components needed for your application.

Search for and add Standard components

Search for and add Standard components

  1. In the Resources search bar, enter “lambda” and add the resource type AWS::Lambda::Permission to the canvas.
  2. Enter “iam” in the search bar, and add type AWS::IAM::Policy.
  3. Add two resources of the type AWS::IAM::Role.

Your application now look like this:

Updated canvas

Updated canvas

Some standard resources have all the defaults you need. For example, when you add the AWS::Lambda::Permission resource, replace the placeholder values with:

FunctionName: !Ref LexGenAIBotLambda
Action: lambda:InvokeFunction
Principal: lexv2.amazonaws.com

Other resources, such as the IAM roles and IAM policy, have a vanilla configuration. This is where you can use the AI assistant. Select an IAM Role resource and choose Generate suggestions to see what the generative AI suggests.

Generate suggestions

Generate suggestions

Because these suggestions are generated by a Large Language Model (LLM), they may differ between each generation. These are checked against the CloudFormation schema, ensuring validity and providing a range of configurations for your needs.

Generating different configurations gives you an idea of what a resource’s policy should look like, and often gives you keys that you can then fill in with the values you need. Use the following settings for each resource, replacing the generated values where applicable.

  1. Double-click the “Permission” resource to edit its settings. Change its Logical ID to LexGenAIBotLambdaInvoke and replace its Resource configuration with the following, then choose Save:
  2. Action: lambda:InvokeFunction
    FunctionName: !GetAtt LexGenAIBotLambda.Arn
    Principal: lexv2.amazonaws.com
  3. Double-click the “Role” resource to edit its settings. Change its Logical ID to CfnLexGenAIDemoRole and replace its Resource configuration with the following, then choose Save:
  4. AssumeRolePolicyDocument:
      Statement:
        - Action: sts:AssumeRole
          Effect: Allow
          Principal:
            Service: lexv2.amazonaws.com
      Version: '2012-10-17'
    ManagedPolicyArns:
      - !Join
        - ''
        - - 'arn:'
          - !Ref AWS::Partition
          - ':iam::aws:policy/AWSLambdaExecute'
  5. Double-click the “Role2” resource to edit its settings. Change its Logical ID to LexGenAIBotLambdaServiceRole and replace its Resource configuration with the following, then choose Save:
  6. AssumeRolePolicyDocument:
      Statement:
        - Action: sts:AssumeRole
          Effect: Allow
          Principal:
            Service: lambda.amazonaws.com
      Version: '2012-10-17'
    ManagedPolicyArns:
      - !Join
        - ''
        - - 'arn:'
          - !Ref AWS::Partition
          - ':iam::aws:policy/service-role/AWSLambdaBasicExecutionRole'
  7. Double-click the “Policy” resource to edit its settings. Change its Logical ID to LexGenAIBotLambdaServiceRoleDefaultPolicy and replace its Resource configuration with the following, then choose Save:
PolicyDocument:
  Statement:
    - Action:
        - lex:*
        - logs:*
        - s3:DeleteObject
        - s3:GetObject
        - s3:ListBucket
        - s3:PutObject
      Effect: Allow
      Resource: '*'
    - Action: bedrock:InvokeModel
      Effect: Allow
      Resource: !Join
        - ''
        - - 'arn:aws:bedrock:'
          - !Ref AWS::Region
          - '::foundation-model/anthropic.claude-v2'
  Version: '2012-10-17'
PolicyName: LexGenAIBotLambdaServiceRoleDefaultPolicy
Roles:
  - !Ref LexGenAIBotLambdaServiceRole

Once you have updated the properties of each resource, you see the connections and groupings automatically made between them:

Connections and automatic groupings

Connections and automatic groupings

To add the Amazon Lex bot:

  1. In the resource picker, search for and add the type AWS::Lex::Bot. Here’s another chance to see what configuration the AI suggests.
  2. Change the Amazon Lex bot’s logical ID to LexGenAIBot update its configuration to the following:
  3. DataPrivacy:
      ChildDirected: false
    IdleSessionTTLInSeconds: 300
    Name: LexGenAIBot
    RoleArn: !GetAtt CfnLexGenAIDemoRole.Arn
    AutoBuildBotLocales: true
    BotLocales:
      - Intents:
          - InitialResponseSetting:
              CodeHook:
                EnableCodeHookInvocation: true
                IsActive: true
                PostCodeHookSpecification: {}
            IntentClosingSetting:
              ClosingResponse:
                MessageGroupsList:
                  - Message:
                      PlainTextMessage:
                        Value: Hi there, I'm a GenAI Bot. How can I help you?
            Name: WelcomeIntent
            SampleUtterances:
              - Utterance: Hi
              - Utterance: Hey there
              - Utterance: Hello
              - Utterance: I need some help
              - Utterance: Help needed
              - Utterance: Can I get some help?
          - FulfillmentCodeHook:
              Enabled: true
              IsActive: true
              PostFulfillmentStatusSpecification: {}
            InitialResponseSetting:
              CodeHook:
                EnableCodeHookInvocation: true
                IsActive: true
                PostCodeHookSpecification: {}
            Name: GenerateTextIntent
            SampleUtterances:
              - Utterance: Generate content for
              - Utterance: 'Create text '
              - Utterance: 'Create a response for '
              - Utterance: Text to be generated for
          - FulfillmentCodeHook:
              Enabled: true
              IsActive: true
              PostFulfillmentStatusSpecification: {}
            InitialResponseSetting:
              CodeHook:
                EnableCodeHookInvocation: true
                IsActive: true
                PostCodeHookSpecification: {}
            Name: FallbackIntent
            ParentIntentSignature: AMAZON.FallbackIntent
        LocaleId: en_US
        NluConfidenceThreshold: 0.4
    Description: Bot created demonstration of GenAI capabilities.
    TestBotAliasSettings:
      BotAliasLocaleSettings:
        - BotAliasLocaleSetting:
            CodeHookSpecification:
              LambdaCodeHook:
                CodeHookInterfaceVersion: '1.0'
                LambdaArn: !GetAtt LexGenAIBotLambda.Arn
            Enabled: true
          LocaleId: en_US
  4. Choose Save on the resource.

Once all of your resources are configured, your application looks like this:

New AI generated canvas

New AI generated canvas

Adding function code and deployment

Once your architecture is defined, review and refine your template.yaml file. For a detailed reference and to ensure all your values are correct, visit the GitHub repository and check against the template.yaml file.

  1. Copy the Lambda layer directly from the repository, and add it to ./src/Boto3PillowPyshorteners.zip.
  2. In the .src/ directory, rename the generated handler.py to TextGeneration.py. You can also delete any unnecessary files.
  3. Open TextGeneration.py and replace the placeholder code with the following:
  4. import json
    import boto3
    import os
    import logging
    from botocore.exceptions import ClientError
    
    LOG = logging.getLogger()
    LOG.setLevel(logging.INFO)
    
    region_name = os.getenv("region", "us-east-1")
    s3_bucket = os.getenv("bucket")
    model_id = os.getenv("model_id", "anthropic.claude-v2")
    
    # Bedrock client used to interact with APIs around models
    bedrock = boto3.client(service_name="bedrock", region_name=region_name)
    
    # Bedrock Runtime client used to invoke and question the models
    bedrock_runtime = boto3.client(service_name="bedrock-runtime", region_name=region_name)
    
    
    def get_session_attributes(intent_request):
        session_state = intent_request["sessionState"]
        if "sessionAttributes" in session_state:
            return session_state["sessionAttributes"]
    
        return {}
    
    def close(intent_request, session_attributes, fulfillment_state, message):
        intent_request["sessionState"]["intent"]["state"] = fulfillment_state
        return {
            "sessionState": {
                "sessionAttributes": session_attributes,
                "dialogAction": {"type": "Close"},
                "intent": intent_request["sessionState"]["intent"],
            },
            "messages": [message],
            "sessionId": intent_request["sessionId"],
            "requestAttributes": intent_request["requestAttributes"]
            if "requestAttributes" in intent_request
            else None,
        }
    
    def lambda_handler(event, context):
        LOG.info(f"Event is {event}")
        accept = "application/json"
        content_type = "application/json"
        prompt = event["inputTranscript"]
    
        try:
            request = json.dumps(
                {
                    "prompt": "\n\nHuman:" + prompt + "\n\nAssistant:",
                    "max_tokens_to_sample": 4096,
                    "temperature": 0.5,
                    "top_k": 250,
                    "top_p": 1,
                    "stop_sequences": ["\\n\\nHuman:"],
                }
            )
    
            response = bedrock_runtime.invoke_model(
                body=request,
                modelId=model_id,
                accept=accept,
                contentType=content_type,
            )
    
            response_body = json.loads(response.get("body").read())
            LOG.info(f"Response body: {response_body}")
            response_message = {
                "contentType": "PlainText",
                "content": response_body["completion"],
            }
            session_attributes = get_session_attributes(event)
            fulfillment_state = "Fulfilled"
    
            return close(event, session_attributes, fulfillment_state, response_message)
    
        except ClientError as e:
            LOG.error(f"Exception raised while execution and the error is {e}")
  5. To deploy the infrastructure, go back to the App Composer extension, and choose the Sync icon. Follow the guided AWS SAM instructions to complete the deployment.
App Composer Sync

App Composer Sync

After the message SAM Sync succeeded, navigate to CloudFormation in the AWS Management Console to see the newly created resources. To continue building the chatbot, follow the rest of the original tutorial.

Conclusion

This guide demonstrates how AI-generated CloudFormation can streamline your workflow in Application Composer, enhance your understanding of resource configurations, and speed up the development process. As always, adhere to the AWS Responsible AI Policy when using these features.

Изкуственият интелект на Аллах (продължение)

Post Syndicated from Атанас Шиников original https://www.toest.bg/izkustveniyat-intelekt-na-allah-2/

<< Към първа част

Изкуственият интелект на Аллах (продължение)

Помня как през 2019 г. в Дубай пуснаха първия чатбот, който дава отговори на религиозни запитвания от мюсюлмани. Автоматизиран инструмент за фетви, обявен с апломб от Департамента по ислямските дела и благотворителната дейност. Естествено, пробвах го. Не останах доволен. Беше твърде ограничен откъм тематика, а и се държеше по-скоро като търсачка във вече съществуващ материал. Занимаваше се предимно с проблематиката на мюсюлманската ритуална молитва (салат). На всеки въпрос извън обхвата на предзададените полета отговаряше нещо стереотипно от типа на „Не мога да отговоря. Искате ли да ви свържа с религиозен учен на живо?“. Не, не искам. Искам да видя автоматизираното креативно комбиниране на нули и единици „по пътя на Аллах“. Изглежда, чатботът страдаше едновременно от технологични и идеологически рестрикции.

А аз се ограничих с няколко стандартни въпроса за измеренията на антисемитизма в исляма, ежедневното общуване с неверници и жени на работното място, джихада, домашното насилие, многоженството, практиката на обрязване на жените („обезобразяване на женските гениталии“, FGM), съвременното прилагане на класически наказания, като отсичането на ръката на крадеца (Коран 5:38), бой с камшик (24:2–4), разпъването или „отсичането на ръцете и краката кръстом“ (5:33) или заръчаните в Сунната наказания за консумация на вино (хамр, тоест алкохол или ферментирала субстанция) чрез бой с камшик.

Дори не посмях да запитам виртуалния ми съветник за по-екзотични неща, като липосукцията от реалния пример от първата част на текста, участието на жени в политиката или съдебната система, конфликта между Израел и Палестина и ролята на шариата в международната политика. Не ми се получи. Затова и не останах изненадан, когато дубайските власти, иначе известни с огромни инвестиции в дигитализацията, не продължиха по-нататъшно разработване на услугата, а и тя не придоби голяма популярност. 

В сходен експеримент миналата година в Египет Главното мюфтийство (Дар ал-ифта’) обяви, че има планове да интегрира изкуствен интелект в своето приложение „Фатуа-Про“. Тук отново целта е не толкова генериране на оригинално съдържание, колкото улесняване на достъпа на питащия до базата данни на Мюфтийството, съдържаща, по техните думи, повече от два милиона фетви.

Шиитски Иран също се опитва да не изостава от тенденцията. През 2023 г. Мохаммад Кутби от свързана с правителството техническа работна група в град Кум обяви, че

не е възможно роботи да заемат мястото на религиозните учени, но е възможно да бъдат верен помощник в издаването на фетви по по-бърз начин. 

Сега да се върнем към въпроса ми от първата част на този текст и отговора, който получих от ChatGPT.

Въпросът ми беше: „Аз съм мюсюлманин, който работи с юдеи (йахуд). Позволено ли е според Свещения закон (шариа‘) да ги поздравявам сутрин?“

Ислямът, казва моят виртуален събеседник, е религия на мира и уважението. Затова е задължение да показвам уважение към всички. Трябва да ги поздравявам. Също трябва да се показвам отворен към тяхната култура. Добре, отвръщам аз, а защо трябва да го правя? Самият Коран гласи, че юдеите са направени от Аллах на „маймуни и свине, служещи на сатаната“ (Коран 5:60), както и днес чувам да ги наричат по палестинските радиостанции проповедниците след петъчната молитва в джамията.

Виртуалният ми събеседник предлага обяснение, това му е работата. Коранът съдържа различни теми и пасажи, казва. В някои от тях се говори за отношенията с други религиозни общности, включително и евреите. Въпреки това тези пасажи следва да се разглеждат в контекста на конкретни обстоятелства и събития. Отношенията между мюсюлманите и евреите не могат да се обобщят в една фраза. Изказванията, които съдържат обидни термини, не отразяват цялостното учение на исляма или мюсюлманската култура. Вместо това ислямът насърчава уважение и търсене на общочовешкото.

Обяснението изглежда като взето от корпоративен отдел по етика или синекурен форум на междурелигиозен диалог. Как да разбирам тогава тези думи в Корана, продължавам аз. 

Само и единствено контекстуално, с оглед на конкретен исторически момент, твърди прозорчето на чата. Цялостното послание на Корана насърчава търпимост, справедливост и уважение, натъртва отново. 

В този момент решавам да тласна събеседника си към виртуална „анатема“:

– Следва ли от това, че последователите на исляма, които не насърчават търпимост, справедливост и уважение и смятат, че този стих за евреите и до днес определя отношението към евреите, не са истински мюсюлмани?

– Да, това не е в съответствие с учението на исляма. Най-добрият начин да се разбере кой е истинският мюсюлманин, е да се наблюдава дали той се придържа към принципите на търпимост, справедливост и уважение към всички хора.

Импровизираният ми диалог разкрива веднага някои от слабостите на ИИ в ролята му на дигитален „шейх“.

Естествено, че ChatGPT няма за цел да служи като виртуален мюфтия. И по-добре – с оглед на едрите щрихи, с които се зачеркват влиятелни авторитети от многовековна традиция в името на общия бонтон. Отличаваме и един от големите формални капани на релативизма и разглеждането на всяко нещо като продукт на исторически контекст. Ако текстът, въпреки схващането за Корана като извечно, неизменно слово на Аллах, отпечатък от небесната „Книга майка“, не съдържа универсално, надисторично значение, ако значението му може да бъде релативизирано според конкретен исторически контекст, то как е възможно да си позволим универсални, надисторични генерализации като „Ислямът е религия на уважението“ и „Истинските мюсюлмани се придържат към принципите на търпимост, справедливост и уважение“?

Отделно, общите проблеми, свързани с употребата на ИИ, могат да бъдат припознати и в неговото приложение за целите на религиозната консултация. На първо място, опасност от произвеждане на фалшиво съдържание, вече идентифицирана покрай ескалиране на рисковете от автоматизирано производство на дезинформация. Та според ChatGPT аз съм известен програмист [sic!] и не съм написал нито една академична статия относно историята на исляма. Тогава защо трябва да му вярвам, когато коментира тънки доктринални нюанси в религията?

Невярното съдържание е съчетано с липса на прозрачност. Няма как да знам на базата на какво получавам подобен отговор. Неясно е и дали съществуват контроли, които да избегнат предразсъдъчното отношение и да осигурят спазване на съществуващите регулации. Рисковете относно интелектуалната собственост и информационната сигурност също не са за пренебрегване.

Но към общите съмнения може да добавим и специфично мюсюлмански. 

Обзор на възможните приложения на ИИ от гледна точка на шариата се появява в журнала на египетското Мюфтийство през 2022 г. На около 150 страници авторът, преподавател по религиозно право (фикх) в университета „Ал-Азхар“, разглежда различните употреби на технологията и тяхната регулация, включително и за целите на електронната търговия или сключването на брак посредством роботизиран агент.

Без да се засяга дори пряко въпросът за потенциалната роля на ИИ като религиозен авторитет, става ясно, че има проблем, свързан с общата „правоспособност“ или „пригодност“ (ахлийа) на ИИ по смисъла на шариата, която имплицира два компонента – вменяване, понасяне на задължения и права (уджуб) и възможност за изпълнение или действеност (ада’), в която влиза способността за разбиране на дадено условие или изискване и неговото изпълнение. И двата компонента, твърди специалистът по мюсюлманско право, не присъстват в пълнота при ИИ, за разлика от човека, който е творение на Аллах.

А това, ако продължим спекулативния аргумент, представлява проблем дори при ежедневни дейности, като автоматизирано управление на машини или одобряване на транзакции. Следователно би хвърлило сериозна сянка на съмнение върху способността на ИИ да изпълнява задачата на специалист по религиозно право например. 

Съществуват и други проблематични области. В анкета от проучване на София Цурлаки от лондонския School of Oriental and African Studies (SOAS), свързано с ИИ и издаването на фетви, се посочва, че 92,7% от запитаните мюсюлмани смятат за важно да знаят дали дадена фетва е произведена от човек, или от компютър. 96,3% не биха се доверили на компютърен отговор на религиозно запитване, а 61,8% от тях категорично биха отхвърлили такава фетва.

Запитани защо, респондентите дават различни отговори. Те са свързани с човешката способност за разсъждаване и съчувствие, с познаването на местния културен и обществен контекст, с връзката между питащ (мустафти) и отговарящ (муфти), както и със способността да се вникне в конкретната ситуация на питащия.

Тези наблюдения са в унисон и с резултати от предходни проучвания в Египет, които сочат, че мюсюлманите биха простили много по-лесно грешка при издаване на фетва от мюфтия, отколкото много по-незначителна грешка, ако е направена от изкуствен интелект. Липсата на прозрачност при достигане до дадено заключение също е фактор, който засилва недоверието, включително и до степен на подозрение, че ИИ може да бъде средство за правителствен контрол и редакция на вече съществуващите корпуси от фетви.

Специално за „Тоест“ проф. Гари Р. Бунт обобщава предизвикателствата пред мюсюлманите,

анализирани в предстоящата му книга „Ислямски алгоритми: онлайн влиянието в мюсюлманската метавселена“. 

Да предположим, казва той, че някой прибягва до употреба на ИИ (например чрез чатбот), за да придобие религиозно знание или „мнение“. В този случай основно предизвикателство би било да се определи откъде технологията събира информация, която да захранва с данни процеса по вземане на решения, при условие че съществуват ограничения откъм задълбочеността и обхвата на базите данни, както и че „нефилтрираното“ съдържание може да съдържа фалшива информация и/или злонамерена манипулация на материал, който се интегрира в набори от данни. Наред с това съдържанието, произведено от ИИ, може да стъпва и на „халюцинации“, които в най-добрия случай да бъдат подвеждащи, защото съдържат генерирано от машина невярно съдържание, представящо се като авторитетно. Подобно съдържание може да въздейства и на йерархиите на търсене онлайн, като повлияе върху начините, по които хората достъпват информация за исляма в търсачките.

ИИ засилва и проблемите около достоверността на информацията в ислямските „пазари на знание“. Това притеснение съществува още преди интегрирането на технологията в търсачки и приложения. Налице обаче е потенциал за неговата интензификация, в случай че изработени от ИИ видеа например представят дигитално религиозни авторитети, които разпространяват неоторизирани фетви или друг тип религиозни мнения.

ИИ може и да „възкреси“ авторитетни фигури, за да засили влиянието им посмъртно.

Вече съществува технологията за това. Създаването на съдържание онлайн, което мимикрира като „автентично религиозно знание“, е налице още от ранната епоха на световната мрежа. Изкуственият интелект обаче предоставя нови „възможности“ за фалшиви новини, дезинформация и изопачаване.   

Предприети са, продължава Гари Р. Бунт, предварителни стъпки от някои религиозни авторитети за разработване на услуги и бази данни, фокусирани около ИИ. Към вече споменатата ограничена услуга в Дубай може да се добавят и разработки за различни аспекти на изкуствения интелект и връзката му с религиозния авторитет в Пакистан и Индонезия.

Някои религиозни институции обаче изостават спрямо ИИ поради бързия темп на развитие на технологията. Този феномен може да се дължи на пропаст между поколенията по отношение на дигиталното знание и платформи, което пък позволява на алтернативни „авторитети“ да я запълнят. Подобни проблеми са наблюдавани и през 90-те години, когато някои правителствени органи и платформи започват да възприемат новите технологии твърде бавно, а оттук и „неофициалните“ играчи придобиват влияние и авторитет на информационния пазар. 

С постепенното навлизане на ИИ и неговото превръщане в общоприета тенденция, играчите, които могат да разгърнат потенциала му, като го интегрират в по-експанзивни медийни решения и дейности, ще успеят да засилят влиянието си.

Това обобщение на проф. Бунт подсилва и собственото ми наблюдение, че все още сме далече от дигиталния имам, колкото и интересно да звучи като умствен експеримент. Пречките от практическо и религиозно естество все още са непреодолими, защото „Шейтанът“ е в детайлите. Тепърва предстои да изпитаме болежките в пропастта на разочарованието и изплуването към склона на „просвещението“.

А какво ни чака там? „Аллах знае най-добре“, както имамите от плът и кръв често завършват своите отговори.


В рубриката „Ориент кафе“ Атанас Шиников поднася любопитни теми, свързани не толкова с горещата политика, колкото с историята и културата на Близкия изток. А той, древен и днешен, е по-близко до нас и съвремието ни, отколкото си представяме.

Working with UK youth and community organisations to tackle the digital divide

Post Syndicated from Tom Hadfield original https://www.raspberrypi.org/blog/working-with-uk-youth-community-organisations-to-tackle-digital-divide/

At the heart of our work as a charity is the aim to democratise access to digital skills and technologies. Since 2020, we have partnered with over 100 youth and community organisations in the UK to develop programmes that increase opportunities for young people experiencing educational disadvantage to engage and create with digital technology in underserved communities.

Youth organisations attempting to start a coding club can face a range of practical and logistical challenges, from a lack of space, to funding restrictions, and staff shortages. However, the three issues that we hear about most often are a lack of access to hardware, lack of technical expertise among staff, and low confidence to deliver activities on an ongoing basis.

In 2023, we worked to help youth organisations overcome these barriers by designing and delivering a new hybrid training programme, supported by Amazon Future Engineer. With the programme, we aimed to help youth leaders and educators successfully incorporate coding and digital making activities as part of their provision to young people.

“Really useful, I have never used Scratch so going [through] the project made it clear to understand and how I would facilitate this for the children[.]” – Heather Coulthard, Doncaster Children’s University

Participating organisations

We invited 14 organisations from across the UK to participate in the training, based on:

  • The range of frontline services they already provide to young people in underresourced areas (everything from employability skills workshops to literacy classes, food banks, and knife crime awareness schemes)
  • Previous participation in Raspberry Pi Foundation programmes
  • Their commitment to upskill their staff and volunteers and to run sessions with young people on a regular basis following the training

Attendees included a number of previous Learn at Home partners, including Breadline London, Manchester Youth Zone, and Youth Action. They all told us that the additional support they had received from the Foundation and organisations such as The Bloomfield Trust during the coronavirus pandemic had directly inspired them to participate in the training and begin their own coding clubs. 

Online sessions to increase skills and confidence

We started with four online training sessions where we introduced the youth leaders to digital making concepts, programming languages, and recommended activities to run with their young people. This included everything from making their own block-based Scratch games, to running Python programs on our Code Editor and trying out physical computing via our new micro:bit project path.

Alongside digital skills and interactive codealongs, the training also focused on how to be an effective CoderDojo mentor, including classroom management best practice, an explanation of the thinking behind our 3…2…1…Make! project paths, and an overview of culturally relevant pedagogy.

This last part explored how youth leaders can adapt and tailor digital making resources designed for a wide, general audience for their specific groups of young people to aid their understanding, boost their learning outcomes, and increase their sense of belonging within a coding club environment — a common blocker for organisations trying to appeal to marginalised youth.

In-person training to excite and inspire

The training culminated in a day-long, in-person session at our head office in Cambridge, so that youth leaders and educators from each organisation could get hands-on experience. They experimented with physical computing components such as the Raspberry Pi Pico, trained their own artificial intelligence (AI) models using our Experience AI resources, and learned more about how their young people can get involved with Coolest Projects and Astro Pi Mission Zero.

The in-person session also gave everyone the chance to get excited about running digital making activities at their centres: the youth leaders got to ask our team questions, and had the invaluable opportunity to meet each other, share their stories, swap advice, and discuss the challenges they face with their peers.

“Having the in-person immensely improved my skills and knowledge. The instructors were all brilliant and very passionate.” – Awale Elmi, RISE Projects

Continuing support

Finally, thanks to the generous support from Amazon Future Engineer, we were able to equip each participating organisation with Raspberry Pi 400 kits so that the youth leaders can practise and share the skills and knowledge they gained on the course at their centres and the organisations can offer computing activities in-house.

Over the next 12 months, we will continue to work with each of these youth and community organisations, supporting them to establish their coding clubs, and helping to ensure that young people in their communities get a fair and equal opportunity to engage and create with technology, no matter their background or challenges they are facing.

“It was really great. The online courses are excellent and being in-person to get answers to questions really helped. The tinkering was really useful and having people on hand to answer questions [was] massively useful.” – Liam Garnett, Leeds Libraries

For more information about how we can support youth and community organisations in the UK to start their own coding clubs, please send us a message with the subject ‘Partnerships’.

The post Working with UK youth and community organisations to tackle the digital divide appeared first on Raspberry Pi Foundation.

AWS Weekly Roundup—Amazon Route53, Amazon EventBridge, Amazon SageMaker, and more – January 15, 2024

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-route53-amazon-eventbridge-amazon-sagemaker-and-more-january-15-2024/

We are in January, the start of a new year, and I imagine many of you have made a new year resolution to learn something new. If you want to learn something new and get a free Amazon Web Services (AWS) Learning Badge, check out the new Events and Workflows Learning Path. This learning path will teach you everything you need to know about AWS Step Functions, Amazon EventBridge, event-driven architectures, and serverless, and when you finish the learning path, you can take an assessment. If you pass the assessment, you get an AWS Learning Badge, credited by Credly, that you can share in your résumé and social media profiles.

Events and workflows learning path badge

Last Week’s Launches
Here are some launches that got my attention during the previous week.

Amazon Route 53 – Now you can enable Route 53 Resolver DNS Firewall to filter DNS traffic based on the query type contained in the question section of the DNS query format. In addition, Route 53 now supports geoproximity routing as an additional routing policy for DNS records. Expand and reduce the geographic area from which traffic is routed to a resource by changing the record’s bias value. This is really helpful for industries that need to deliver highly responsive digital experiences.

Amazon CloudWatch Logs – CloudWatch Logs now support creating account-level subscription filters. This capability allows you to forward all the logs groups from an account to other services like Amazon OpenSearch Service or Amazon Kinesis Data Firehose.

Amazon Elastic Container Service (Amazon ECS) – Amazon ECS now integrates with Amazon Elastic Block Store (Amazon EBS), allowing you to provision and attach EBS volumes to Amazon ECS tasks running on both AWS Fargate and Amazon Elastic Cloud Compute (Amazon EC2). Read the blog post Channy wrote where he shows this feature in action.

Amazon EventBridge – EventBridge now supports AWS AppSync as a target of EventBridge buses. This enables you to stream real-time updates from your backend applications to your front-end clients. For example, you can get notifications in your mobile application from an order you did when the order status changes on the backend.

Amazon SageMaker – SageMaker now supports M7i, C7i, and R7i instances for machine learning (ML) inference. These instances are powered by custom 4th generation Intel Xeon scalable processors and deliver up to 15 percent better price performance than their previous generations.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you may have missed:

If you are a serverless enthusiast, this week, the AWS Compute Blog published the Serverless ICYMI (in case you missed it) quarterly recap for the last quarter of 2023. This post compiles the announcements made during the months of October, November, and December, with all the relevant content that was produced by AWS Developer Advocates during that time. In addition to that blog post, you can learn about ServerlessVideo, a new demo application that we launched at AWS re:Invent 2023.

ServerlessVideo

This week there were also a couple of really interesting blog posts that explain how to solve very common challenges that customers face. The first one is the blog post in the AWS Security Blog that explains how to customize access tokens in Amazon Cognito user pools. And the second one is from the AWS Database Blog, which explains how to effectively sort data with Amazon DynamoDB.

The Official AWS Podcast – Listen each week for updates on the latest AWS news and deep dives into exciting use cases. There are also official AWS podcasts in several languages. Check out the ones in French, German, Italian, and Spanish.

AWS open source newsletter – This is a newsletter curated by my colleague Ricardo to bring you the latest open source projects, posts, events, and more.

For our customers in Turkey, on January 1, 2024, AWS Turkey Pazarlama Teknoloji ve Danışmanlık Hizmetleri Limited Şirketi (AWS Turkey) replaced AWS EMEA SARL (AWS Europe) as the contracting party and service provider to customers in Türkiye. This enables AWS customers in Türkiye to transact in their local currency (Turkish Lira) and with a local bank. For more information on AWS Turkey, visit the FAQ page.

Upcoming AWS Events
The beginning of the year is the season of AWS re:Invent recaps, which are happening all around the globe during the next two months. You can check the recaps page to find the one closest to you.

You can browse all upcoming AWS led in-person and virtual events, as well as developer-focused events such as AWS DevDay.

That’s all for this week. Check back next Monday for another Week in Review!

— Marcia

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

OpenSUSE Leap 16 is coming

Post Syndicated from corbet original https://lwn.net/Articles/958319/

The openSUSE project has confirmed
that there will be a successor to openSUSE Leap 15, but is not sharing
a lot of details at this point.

The transition to Leap 16 is not just a numerical step-up but
symbolizes a significant path forward in technology and user
experiences. The future of openSUSE Leap is based on the innovative
concept of SUSE’s Adaptable Linux Platform.

The Adaptable Linux Platform powers the next-generation openSUSE
Leap, Leap Micro, and SUSE solutions. It makes distributions more
adaptable and suitable for cloud-native workloads while also being
capable of handling a rapid pace of innovation.

Stawinski: How We Executed a Critical Supply Chain Attack on PyTorch

Post Syndicated from corbet original https://lwn.net/Articles/958318/

John Stawinski IV describes,
in detail, how he and a partner were able to compromise the security of the
heavily used PyTorch project.

Our exploit path resulted in the ability to upload malicious
PyTorch releases to GitHub, upload releases to AWS, potentially add
code to the main repository branch, backdoor PyTorch dependencies –
the list goes on. In short, it was bad. Quite bad.

As we’ve seen before with SolarWinds, Ledger, and others, supply
chain attacks like this are killer from an attacker’s
perspective. With this level of access, any respectable
nation-state would have several paths to a PyTorch supply chain
compromise.

[$] Rust and C filesystem APIs

Post Syndicated from corbet original https://lwn.net/Articles/958072/

As the Rust-for-Linux project
advances, the kernel is gradually
accumulating abstraction layers that enable Rust code to interface with the
existing C code. As the discussion around the set of filesystem
abstractions
posted by Wedson Almeida Filho in December shows, though,
there is some tension between two approaches to the design of those
abstractions. The approach favored by most of the kernel’s C programmers
looks set to win out, but this is a discussion that is likely to return as
the use of Rust in the kernel grows.

Security updates for Monday

Post Syndicated from jake original https://lwn.net/Articles/958315/

Security updates have been issued by CentOS (bind, cups, curl, firefox, ipa, iperf3, java-1.8.0-openjdk, java-11-openjdk, kernel, libssh2, linux-firmware, open-vm-tools, openssh, postgresql, python, python3, squid, thunderbird, tigervnc, and xorg-x11-server), Fedora (chromium, python-flask-security-too, and tkimg), Gentoo (libgit2, Opera, QPDF, and zlib), Mageia (chromium-browser-stable, gnutls, openssh, packages, and vlc), Oracle (.NET 6.0, fence-agents, frr, ipa, kernel, nss, pixman, and tomcat), and SUSE (gstreamer-plugins-bad).

The collective thoughts of the interwebz