Tag Archives: Amazon Redshift

Amazon Redshift continues its price-performance leadership

Post Syndicated from Stefan Gromoll original https://aws.amazon.com/blogs/big-data/amazon-redshift-continues-its-price-performance-leadership/

Data is a strategic asset. Getting timely value from data requires high-performance systems that can deliver performance at scale while keeping costs low. Amazon Redshift is the most popular cloud data warehouse that is used by tens of thousands of customers to analyze exabytes of data every day. We continue to add new capabilities to improve the price-performance ratio for our customers as you bring more data to your Amazon Redshift environments.

This post goes into detail on the analytic workload trends we’re seeing from the Amazon Redshift fleet’s telemetry data, new capabilities we have launched to improve Amazon Redshift’s price-performance, and the results from the latest benchmarks derived from TPC-DS and TPC-H, which reenforce our leadership.

Data-driven performance optimization

We relentlessly focus on improving Amazon Redshift’s price-performance so that you continue to see improvements in your real-world workloads. To this end, the Amazon Redshift team takes a data-driven approach to performance optimization. Werner Vogels discussed our methodology in Amazon Redshift and the art of performance optimization in the cloud, and we have continued to focus our efforts on using performance telemetry from our large customer base to drive the Amazon Redshift performance improvements that matter most to our customers.

At this point, you might ask why does price-performance matter? One critical aspect of a data warehouse is how it scales as your data grows. Will you be paying more per TB as you add more data, or will your costs remain consistent and predictable? We work to make sure that Amazon Redshift delivers not only strong performance as your data grows, but also consistent price-performance.

Optimizing high-concurrency, low-latency workloads

One of the trends that we have observed is that customers are increasingly building analytics applications that require high concurrency of low-latency queries. In the context of data warehousing, this can mean hundreds or even thousands of users running queries with response time SLAs of under 5 seconds.

A common scenario is an Amazon Redshift-powered business intelligence dashboard that serves analytics to a very large number of analysts. For example, one of our customers processes foreign exchange rates and delivers insights based on this data to their users using an Amazon Redshift-powered dashboard. These users generate an average of 200 concurrent queries to Amazon Redshift that can spike to 1,200 concurrent queries at the open and close of the market, with a P90 query SLA of 1.5 seconds. Amazon Redshift is able to meet this requirement, so this customer can meet their business SLAs and provide the best service possible to their users.

A specific metric we track is the percentage of runtime across all clusters that is spent on short-running queries (queries with runtime less than 1 second). Over the last year, we’ve seen a significant increase in short query workloads in the Amazon Redshift fleet, as shown in the following chart.
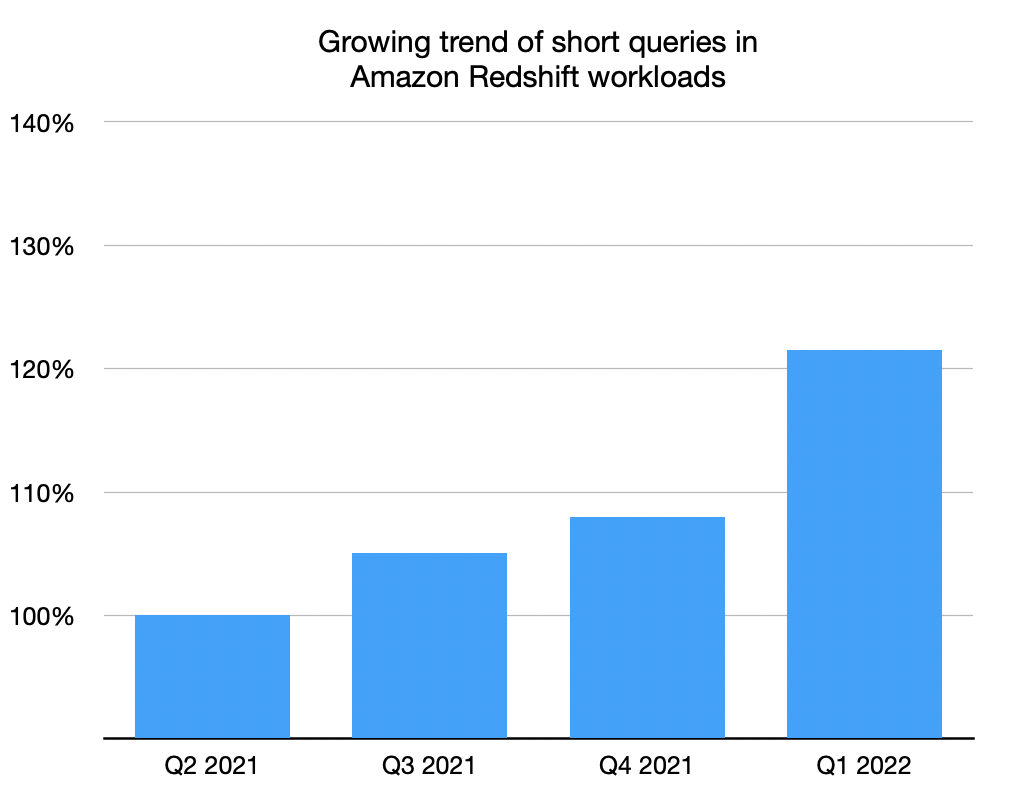
As we started to look deeper into how Amazon Redshift ran these kinds of workloads, we discovered several opportunities to optimize performance to give you even better throughput on short queries:

  • We significantly reduced Amazon Redshift’s query-planning overhead. Even though this isn’t large, it can be a significant portion of the runtime of short queries.
  • We improved the performance of several core components for situations where many concurrent processes contend for the same resources. This further reduced our query overhead.
  • We made improvements that allowed Amazon Redshift to more efficiently burst these short queries to concurrency scaling clusters to improve query parallelism.

To see where Amazon Redshift stood after making these engineering improvements, we ran an internal test using the Cloud Data Warehouse Benchmark derived from TPC-DS (see a later section of this post for more details on the benchmark, which is available in GitHub). To simulate a high-concurrency, low-latency workload, we used a small 10 GB dataset so that all queries ran in a few seconds or less. We also ran the same benchmark against several other cloud data warehouses. We didn’t enable auto scaling features such as concurrency scaling on Amazon Redshift for this test because not all data warehouses support it. We used an ra3.4xlarge Amazon Redshift cluster, and sized all other warehouses to the closest matching price-equivalent configuration using on-demand pricing. Based on this configuration, we found that Amazon Redshift can deliver up to 8x better performance on analytics applications that predominantly required short queries with low latency and high concurrency, as shown in the following chart.
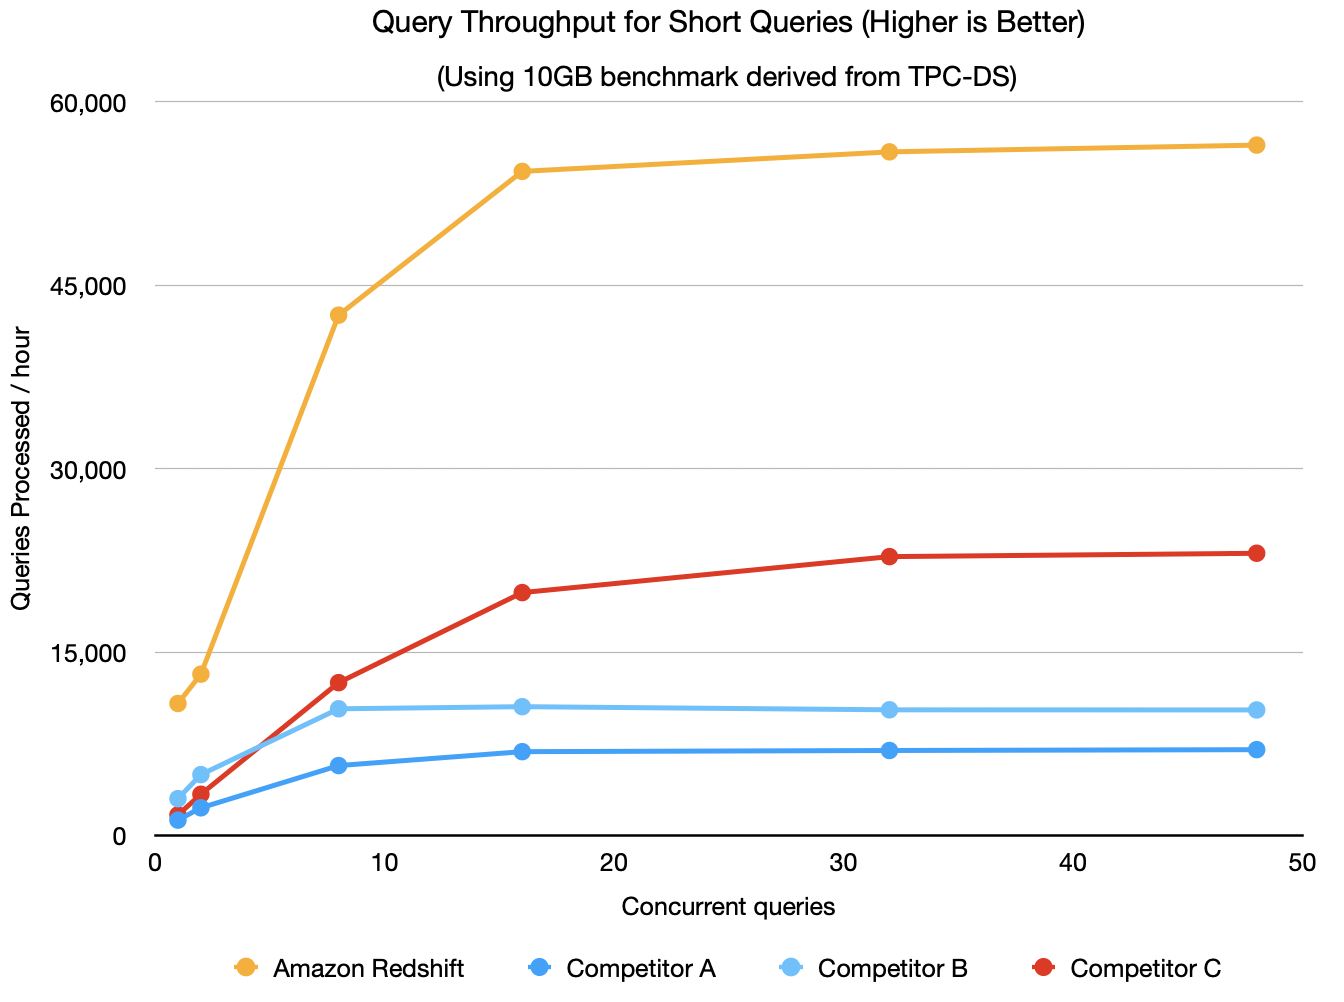
With Concurrency Scaling on Amazon Redshift, throughput can be seamlessly and automatically scaled to additional Amazon Redshift clusters as user concurrency grows. We increasingly see customers using Amazon Redshift to build such analytics applications based on our telemetry data.

This is just a small peek into the behind-the-scenes engineering improvements our team is continually making to help you improve performance and save costs using a data-driven approach.

New features improving price-performance

With the constantly evolving data landscape, customers want high-performance data warehouses that continue to launch new capabilities to deliver the best performance at scale while keeping costs low for all workloads and applications. We have continued to add features that improve Amazon Redshift’s price-performance out of the box at no additional cost to you, allowing you to solve business problems at any scale. These features include the use of best-in-class hardware through the AWS Nitro System, hardware acceleration with AQUA, auto-rewriting queries so that they run faster using materialized views, Automatic Table Optimization (ATO) for schema optimization, Automatic Workload Management (WLM) to offer dynamic concurrency and optimize resource utilization, short query acceleration, automatic materialized views, vectorization and single instruction/multiple data (SIMD) processing, and much more. Amazon Redshift has evolved to become a self-learning, self-tuning data warehouse, abstracting away the performance management effort needed so you can focus on high-value activities like building analytics applications.

To validate the impact of the latest Amazon Redshift performance enhancements, we ran price-performance benchmarks comparing Amazon Redshift with other cloud data warehouses. For these tests, we ran both a TPC-DS-derived benchmark and a TPC-H-derived benchmark using a 10-node ra3.4xlarge Amazon Redshift cluster. To run the tests on other data warehouses, we chose warehouse sizes that most closely matched the Amazon Redshift cluster in price ($32.60 per hour), using published on-demand pricing for all data warehouses. Because Amazon Redshift is an auto-tuning warehouse, all tests are “out of the box,” meaning no manual tunings or special database configurations are applied—the clusters are launched and the benchmark is run. Price-performance is then calculated as cost per hour (USD) times the benchmark runtime in hours, which is equivalent to the cost to run the benchmark.

For both the TPC-DS-derived and TPC-H-derived tests, we find that Amazon Redshift consistently delivers the best price-performance. The following chart shows the results for the TPC-DS-derived benchmark.
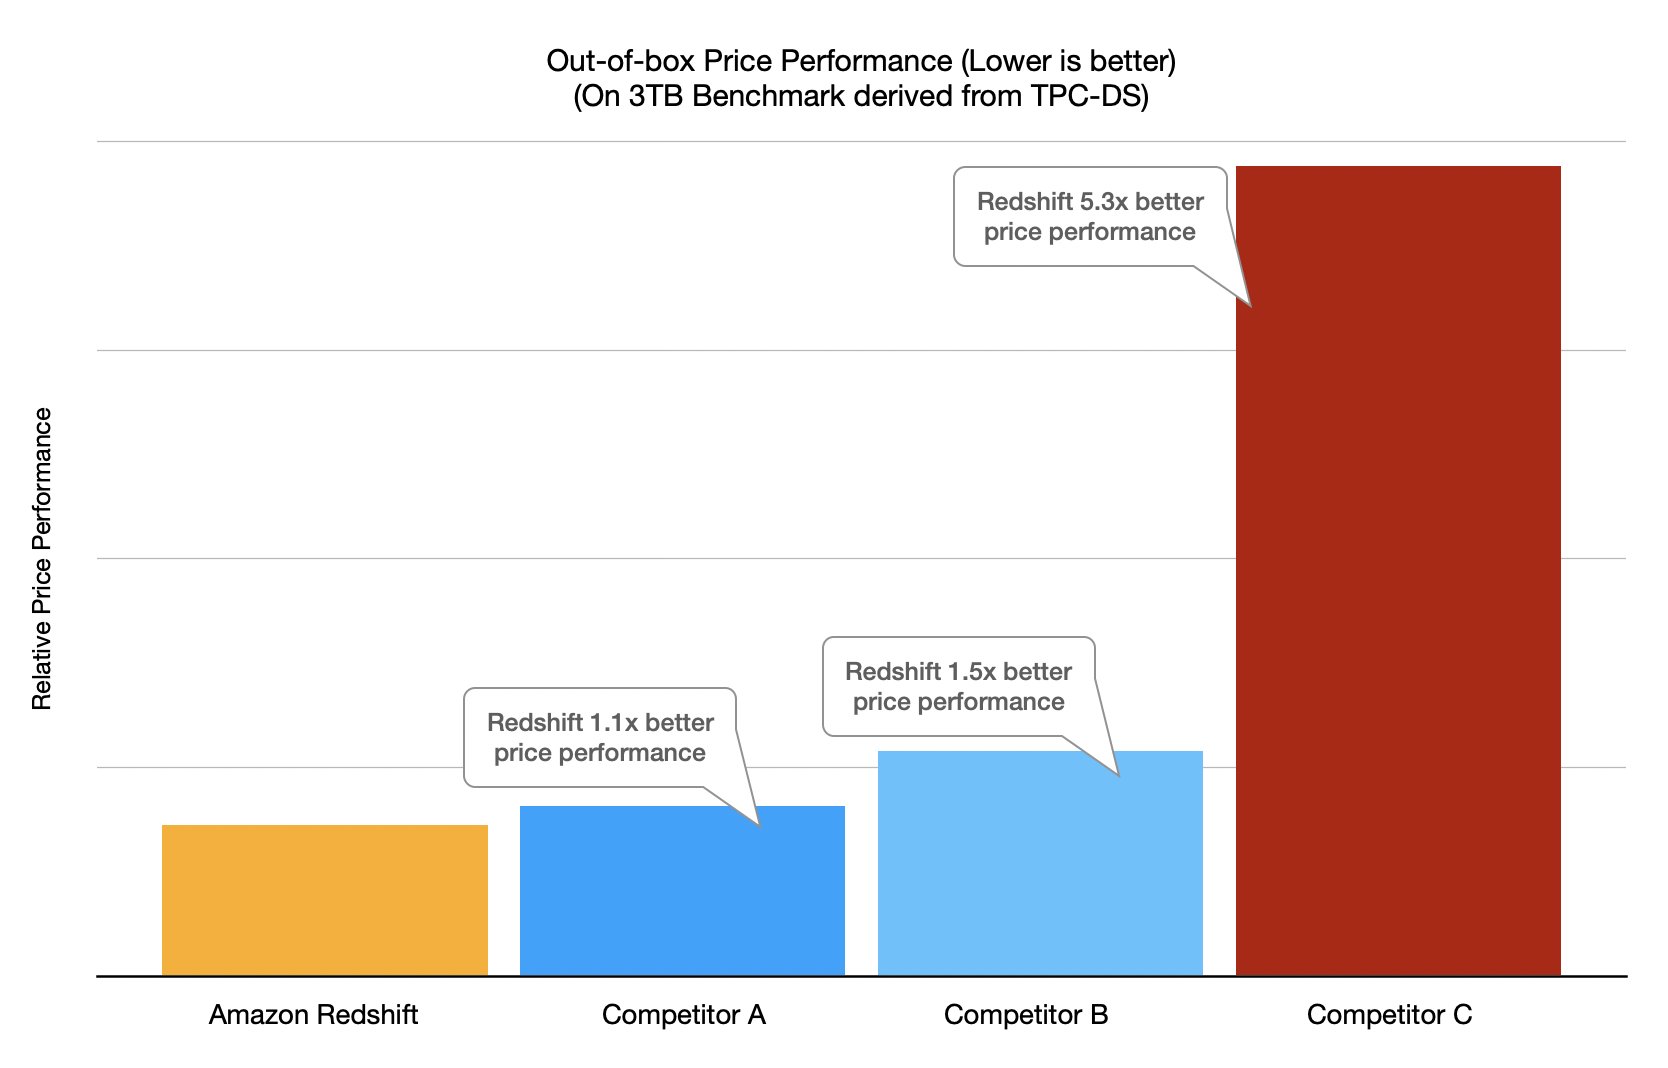
The following chart shows the results for the TPC-H-derived benchmark.
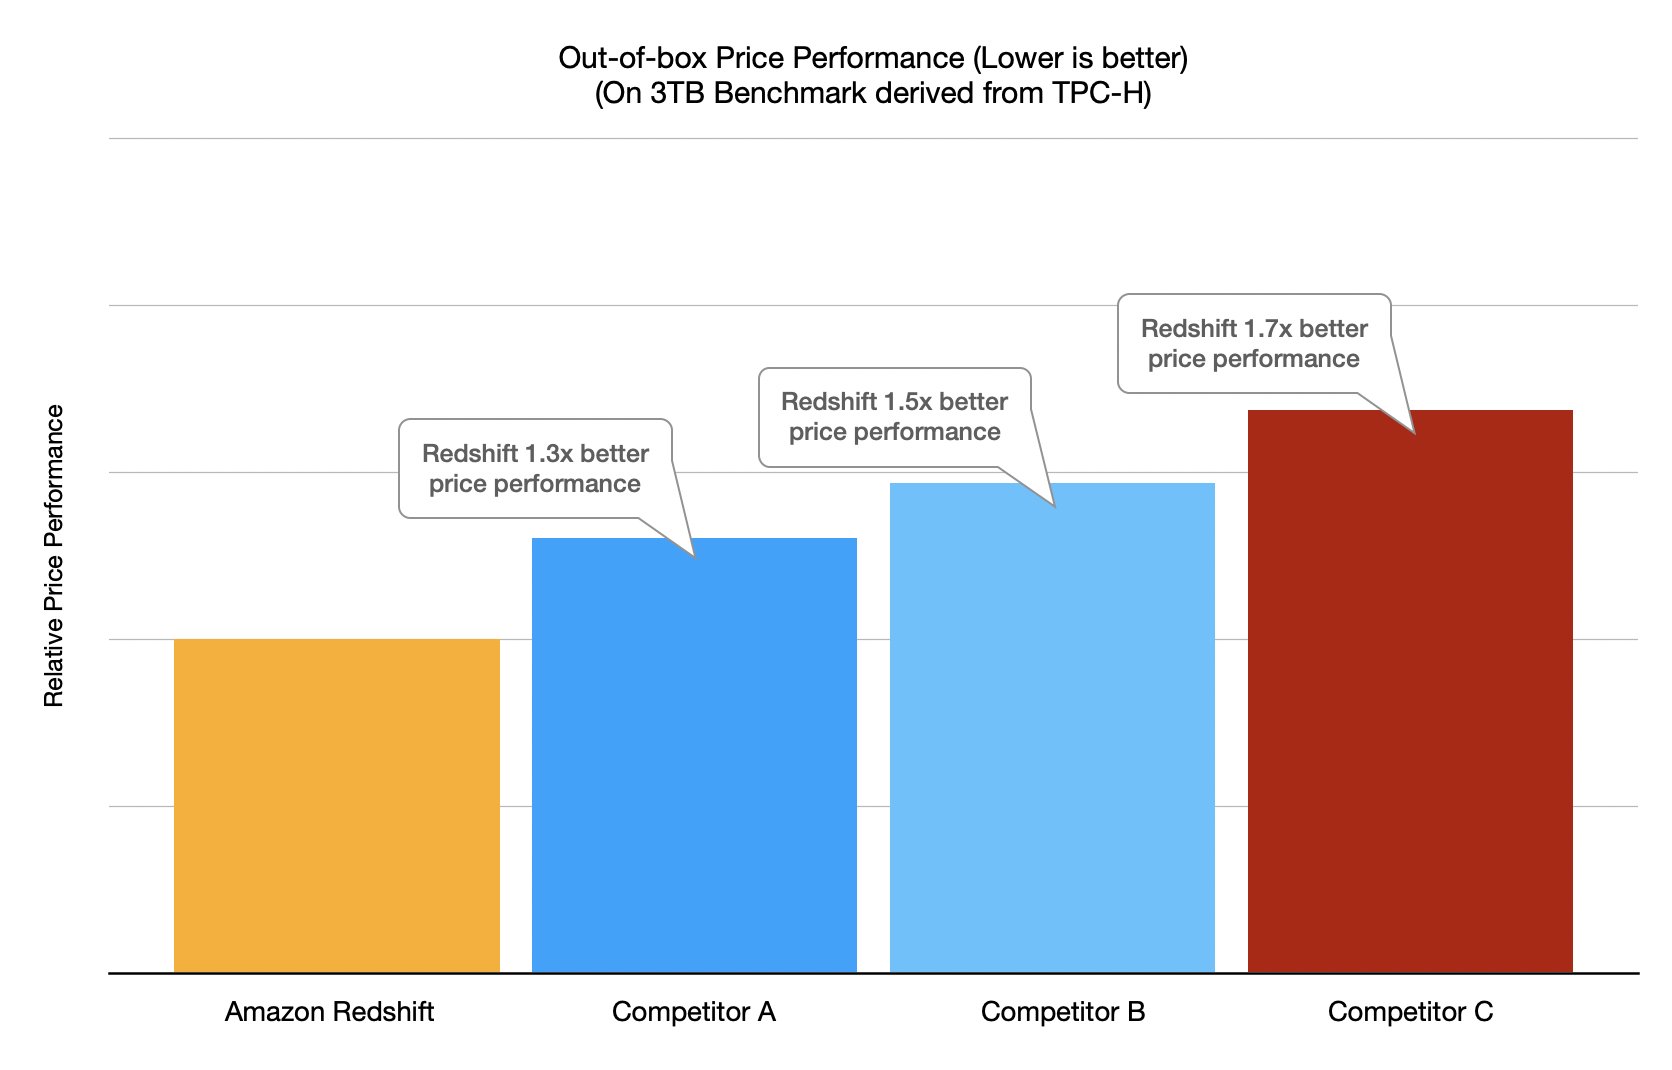
Although these benchmarks reaffirm Amazon Redshift’s price-performance leadership, we always encourage you to try Amazon Redshift using your own proof-of-concept workloads as the best way to see how Amazon Redshift can meet your data needs.

Find the best price-performance for your workloads

The benchmarks used in this post are derived from the industry-standard TPC-DS and TPC-H benchmarks, and have the following characteristics:

  • The schema and data are used unmodified from TPC-DS and TPC-H.
  • The queries are used unmodified from TPC-DS and TPC-H. TPC-approved query variants are used for a warehouse if the warehouse doesn’t support the SQL dialect of the default TPC-DS or TPC-H query.
  • The test includes only the 99 TPC-DS and 22 TPC-H SELECT queries. It doesn’t include maintenance and throughput steps.
  • Three power runs (single stream) were run with query parameters generated using the default random seed of the TPC-DS and TPC-H kits.
  • The primary metric of total query runtime is used when calculating price-performance. The runtime is taken as the best of the three runs.
  • Price-performance is calculated as cost per hour (USD) times the benchmark runtime in hours, which is equivalent to cost to run the benchmark. Published on-demand pricing is used for all data warehouses.

We call this benchmark the Cloud Data Warehouse Benchmark, and you can easily reproduce the preceding benchmark results using the scripts, queries, and data available on GitHub. It is derived from the TPC-DS and TPC-H benchmarks as described earlier, and as such is not comparable to published TPC-DS or TPC-H results, because the results of our tests don’t comply with the specification.

Each workload has unique characteristics, so if you’re just getting started, a proof of concept is the best way to understand how Amazon Redshift performs for your requirements. When running your own proof of concept, it’s important to focus on the right metrics—query throughput (number of queries per hour) and price-performance. You can make a data-driven decision by running a proof of concept on your own or with assistance from AWS or a system integration and consulting partner.

Conclusion

This post discussed the analytic workload trends we’re seeing from Amazon Redshift customers, new capabilities we have launched to improve Amazon Redshift’s price-performance, and the results from the latest benchmarks.

If you’re an existing Amazon Redshift customer, connect with us for a free optimization session and briefing on the new features announced at AWS re:Invent 2021. To stay up to date with the latest developments in Amazon Redshift, follow the What’s New in Amazon Redshift feed.


About the Authors

Stefan Gromoll is a Senior Performance Engineer with Amazon Redshift where he is responsible for measuring and improving Redshift performance. In his spare time, he enjoys cooking, playing with his three boys, and chopping firewood.
Ravi Animi is a Senior Product Management leader in the Redshift Team and manages several functional areas of the Amazon Redshift cloud data warehouse service including performance, spatial analytics, streaming ingestion and migration strategies. He has experience with relational databases, multi-dimensional databases, IoT technologies, storage and compute infrastructure services and more recently as a startup founder using AI/deep learning, computer vision, and robotics.
Florian Wende is a Performance Engineer with Amazon Redshift.

Automate notifications on Slack for Amazon Redshift query monitoring rule violations

Post Syndicated from Dipankar Kushari original https://aws.amazon.com/blogs/big-data/automate-notifications-on-slack-for-amazon-redshift-query-monitoring-rule-violation/

In this post, we walk you through how to set up automatic notifications of query monitoring rule (QMR) violations in Amazon Redshift to a Slack channel, so that Amazon Redshift users can take timely action.

Amazon Redshift is a fully managed, petabyte-scale data warehouse service in the cloud. With Amazon Redshift, you can analyze your data to derive holistic insights about your business and your customers. One of the challenges is to protect the data warehouse workload from poorly written queries that can consume significant resources. Amazon Redshift query monitoring rules are a feature of workload management (WLM) that allow automatic handling of poorly written queries. Rules that are applied to a WLM queue allow queries to be logged, canceled, hopped (only available with manual WLM), or to change priority (only available with automatic WLM). The reason to use QMRs is to protect against wasteful use of the cluster. You can also use these rules to log resource-intensive queries, which provides the opportunity to establish governance for ad hoc workloads.

The Amazon Redshift cluster automatically collects query monitoring rules metrics. This convenient mechanism lets you view attributes like the following:

  • Query runtime, in seconds
  • Query return row count
  • The CPU time for a SQL statement

It also makes Amazon Redshift Spectrum metrics available, such as the number of Redshift Spectrum rows and MBs scanned by a query.

When a query violates a QMR, Amazon Redshift logs the violation into the STL_WLM_RULE_ACTION system view. If the action is aborted for the queries that violate a QMR, end-users see an error that indicates query failure due to violation of QMRs. We recommend that administrative team members periodically examine violations listed in the STL_WLM_RULE_ACTION table and coach the involved end-users on how to avoid future rule violations.

Alternately, a centralized team, using a Slack channel for collaboration and monitoring, can configure Amazon Redshift events and alarms to be sent to their channel, so that they can take timely action. In the following sections, we walk you through how to set up automatic notifications of QMR violations to a Slack channel through the use of Slack events and alarms. This allows Amazon Redshift users to be notified and take timely actions without the need to query the system view.

Solution overview

To demonstrate how you can receive automatic notification to a Slack channel for QMR violation, we have designed the following architecture. As shown in the following diagram, we have mixed workload extract, transform, and load (ETL), business intelligence (BI) dashboards, and analytics applications that are powered by an Amazon Redshift cluster. The solution relies on AWS Lambda and Amazon Simple Notification Service (Amazon SNS) to send notifications of Amazon Redshift QMR violations to Slack.

To implement this solution, you create an Amazon Redshift cluster and attach a custom defined parameter group.

Amazon Redshift provides one default parameter group for each parameter group family. The default parameter group has preset values for each of its parameters, and it can’t be modified. If you want to use different parameter values than the default parameter group, you must create a custom parameter group and then associate your cluster with it.

In the parameter group, you can use automatic WLM and define a few workload queues, such as a queue for processing ETL workloads and a reporting queue for user queries. You can name the default queue adhoc. With automatic WLM, Amazon Redshift determines the optimal concurrency and memory allocation for each query that is running in each queue.

For each workload queue, you can define one or more QMRs. For example, you can create a rule to abort a user query if it runs for more than 300 seconds or returns more than 1 billion rows. Similarly, you can create a rule to log a Redshift Spectrum query that scans more than 100 MB.

The Amazon Redshift WLM evaluates metrics every 10 seconds. It records details about actions that result from QMR violation that is associated with user-defined queues in the STL_WLM_RULE_ACTION system table. In this solution, a Lambda function is scheduled to monitor the STL_WLM_RULE_ACTION system table every few minutes. When the function is invoked, if it finds a new entry, it publishes a detailed message to an SNS topic. A second Lambda function, created as the target subscriber to the SNS topic, is invoked whenever any message is published to the SNS topic. This second function invokes a pre-created Slack webhook, which sends the message that was received through the SNS topic to the Slack channel of your choice. (For more information on publishing messages by using Slack webhooks, see Sending messages using incoming webhooks.)

To summarize, the solution involves the following steps:

  1. Create an Amazon Redshift custom parameter group and add workload queues.
  2. Configure query monitoring rules.
  3. Attach the custom parameter group to the cluster.
  4. Create a SNS topic.
  5. Create a Lambda function and schedule it to run every 5 minutes by using an Amazon EventBridge rule.
  6. Create the Slack resources.
  7. Add an incoming webhook and authorize the Slack app to post messages to a Slack channel.
  8. Create the second Lambda function and subscribe to the SNS topic.
  9. Test the solution.

Create an Amazon Redshift custom parameter group and add workload queues

In this step, you create an Amazon Redshift custom parameter group with automatic WLM enabled. You also create the following queues to separate the workloads in the parameter group:

  • reporting – The reporting queue runs BI reporting queries that are performed by any user who belongs to the Amazon Redshift database group named reporting_group
  • adhoc – The default queue, renamed adhoc, performs any query that is not sent to any other queue

Complete the following steps to create your parameter group and add workload queues:

  1. Create a parameter group, named csblog, with automatic WLM enabled.
  2. On the Amazon Redshift console, select the custom parameter group you created.
  3. Choose Edit workload queues.
  4. On the Modify workload queues page, choose Add queue.
  5. Fill in the Concurrency scaling mode and Query priority fields as needed to create the reporting queue.
  6. Repeat these steps to add the adhoc queue.

For more information about WLM queues, refer to Configuring workload management.

Configure query monitoring rules

In this step, you add QMRs to each workload queue. For instructions, refer to Creating or modifying a query monitoring rule using the console.

For the reporting queue, add the following QMRs:

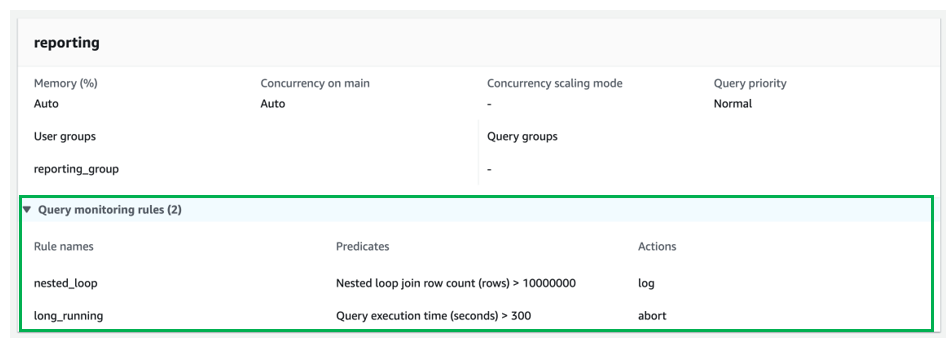
  • nested_loop – Logs any query involved in a nested loop join that results in a row count more than 10,000,000 rows.
  • long_running – Stops queries that run for more than 300 seconds (5 minutes).

For the adhoc queue, add the following QMRs:

  • returned_rows – Stops any query that returns more than 1,000,000 rows back to the calling client application (this isn’t practical and can degrade the end-to-end performance of the application).
  • spectrum_scan – Stops any query that scans more than 1000 MB of data from an Amazon Simple Storage Service (Amazon S3) data lake by using Redshift Spectrum.

Attach the custom parameter group to the cluster

To attach the custom parameter group to your provisioned Redshift cluster, follow the instructions in Associating a parameter group with a cluster. If you don’t already have a provisioned Redshift cluster, refer to Create a cluster.

For this post, we attached our custom parameter group csblog to an already created provisioned Amazon Redshift cluster.

Create an SNS topic

In this step, you create an SNS topic that receives a detailed message of QMR violation from the Lambda function that checks the Amazon Redshift system table for QMR violation entries. For instructions, refer to Creating an Amazon SNS topic.

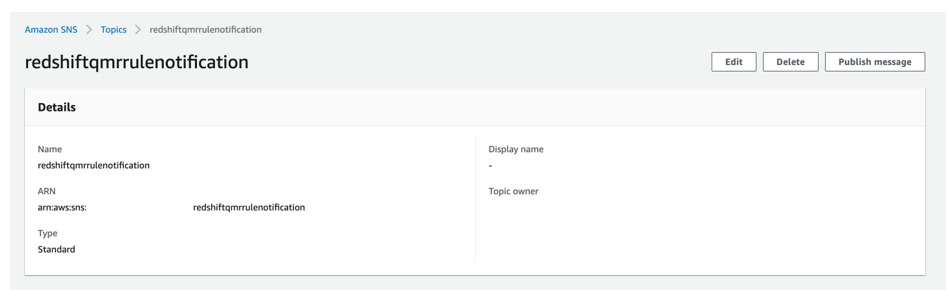
For this post, we created an SNS topic named redshiftqmrrulenotification.

Create a Lambda function to monitor the system table

In this step, you create a Lambda function that monitors the STL_WLM_RULE_ACTION system table. Whenever any record is found in the table since the last time the function ran, the function publishes a detailed message to the SNS topic that you created earlier. You also create an EventBridge rule to invoke the function every 5 minutes.

For this post, we create a Lambda function named redshiftqmrrule that is scheduled to run every 5 minutes via an EventBridge rule named Redshift-qmr-rule-Lambda-schedule. For instructions, refer to Building Lambda functions with Python.

The following screenshot shows the function that checks the pg_catalog.stl_wlm_rule_action table.

To create an EventBridge rule and associate it with the Lambda function, refer to Create a Rule.

The following screenshot shows the EventBridge rule Redshift-qmr-rule-Lambda-schedule, which calls the function every 5 minutes.

We use the following Python 3.9 code for this Lambda function. The function uses an Amazon Redshift Data API call that uses GetClusterCredentials for temporary credentials.

import json
import time
import unicodedata
import traceback
import sys
from pip._internal import main
import urllib3
import os
import boto3
from datetime import datetime

# initiate redshift-data client in boto3
client = boto3.client("redshift-data")

query = "select userid,query,service_class,trim(rule) as rule,trim(action) as action,recordtime from stl_wlm_rule_action WHERE userid > 1 AND recordtime >= current_timestamp AT TIME ZONE 'UTC' - INTERVAL '5 minute' order by recordtime desc;"
sns = boto3.resource('sns')
sns_arn = os.environ['sns_arn']
platform_endpoint = sns.PlatformEndpoint('{sns_arn}'.format(sns_arn = sns_arn))

def status_check(client, query_id):
    desc = client.describe_statement(Id=query_id)
    status = desc["Status"]
    if status == "FAILED":
        raise Exception('SQL query failed:' + query_id + ": " + desc["Error"])
    return status.strip('"')

def execute_sql(sql_text, redshift_database, redshift_user, redshift_cluster_id):
    print("Executing: {}".format(sql_text))
    res = client.execute_statement(Database=redshift_database, DbUser=redshift_user, Sql=sql_text,
                                   ClusterIdentifier=redshift_cluster_id)
    
    query_id = res["Id"]
    print("query id")
    print(query_id)
    done = False
    while not done:
        time.sleep(1)
        status = status_check(client, query_id)
        if status in ("FAILED", "FINISHED"):
            print("status is: {}".format(status))
            break
    return query_id

def publish_to_sns(message):
    try:
        # Publish a message.
        response = platform_endpoint.publish(
                  Subject='Redshift Query Monitoring Rule Notifications',
                  Message=message,
                  MessageStructure='string'

            )
        return  response

    except:
        print(' Failed to publish messages to SNS topic: exception %s' % sys.exc_info()[1])
        return 'Failed'

def lambda_handler(event, context):
    
    rsdb = os.environ['rsdb']
    rsuser = os.environ['rsuser']
    rscluster = os.environ['rscluster']
    #print(query)
    res = execute_sql(query, rsdb, rsuser, rscluster)
    print("res")
    print(res)
    response = client.get_statement_result(
        Id = res
    )
    # datetime object containing current date and time
    now = datetime.now()
    dt_string = now.strftime("%d-%b-%Y %H:%M:%S")
    print(response) 
    if response['TotalNumRows'] > 0:
        messageText = '################## Reporting Begin' + ' [' + str(dt_string) + ' UTC] ##################\n\n'
        messageText = messageText + 'Total number of queries affected by QMR Rule violation for Redshift cluster "' + rscluster + '" is ' + str(len(response['Records'])) + '.' + '\n' + '\n'
        for i in range(len(response['Records'])):
            messageText = messageText + 'It was reported at ' + str(response['Records'][i][5]['stringValue'])[11:19] + ' UTC on ' + str(response['Records'][i][5]['stringValue'])[0:10] + ' that a query with Query ID - ' + str(response['Records'][i][1]['longValue']) + ' had to ' +  str(response['Records'][i][4]['stringValue']) + ' due to violation of QMR Rule "' + str(response['Records'][i][3]['stringValue']) + '".\n'
        messageText = messageText + '\n########################### Reporting End ############################\n\n'
        query_result_json = messageText
        response = publish_to_sns(query_result_json)
    else:
        print('No rows to publish to SNS')

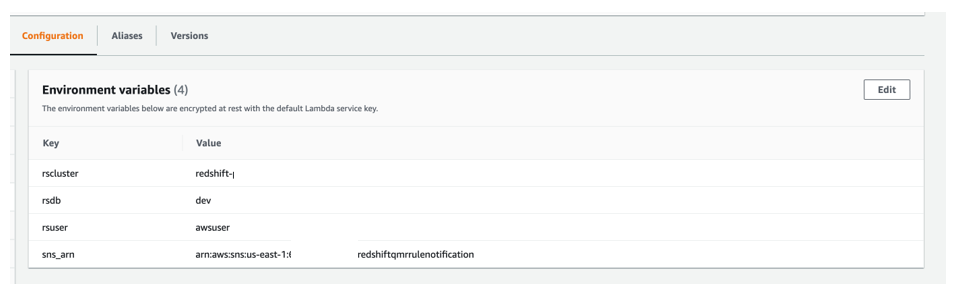
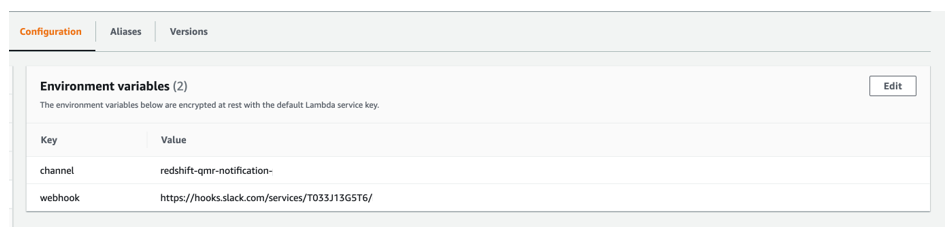
We use four environment variables for this Lambda function:

  • rscluster – The Amazon Redshift provisioned cluster identifier
  • rsdb – The Amazon Redshift database where you’re running these tests
  • rsuser – The Amazon Redshift user who has the privilege to run queries on pg_catalog.stl_wlm_rule_action
  • sns_arn – The Amazon Resource Name (ARN) of the SNS topic that we created earlier

Create Slack resources

In this step, you create a new Slack workspace (if you don’t have one already), a new private Slack channel (only if you don’t have one or don’t want to use an existing one), and a new Slack app in the Slack workspace. For instructions, refer to Create a Slack workspace, Create a channel, and Creating an app.

For this post, we created the following resources in the Slack website and Slack desktop app:

  • A Slack workspace named RedshiftQMR*****
  • A private channel, named redshift-qmr-notification-*****-*******, in the newly created Slack workspace
  • A new Slack app in the Slack workspace, named RedshiftQMRRuleNotification (using the From Scratch option)

Add an incoming webhook and authorize Slack app

In this step, you enable and add an incoming webhook to the Slack workspace that you created. For full instructions, refer to Enable Incoming Webhooks and Create an Incoming Webhook. You also authorize your Slack app so that it can post messages to the private Slack channel.

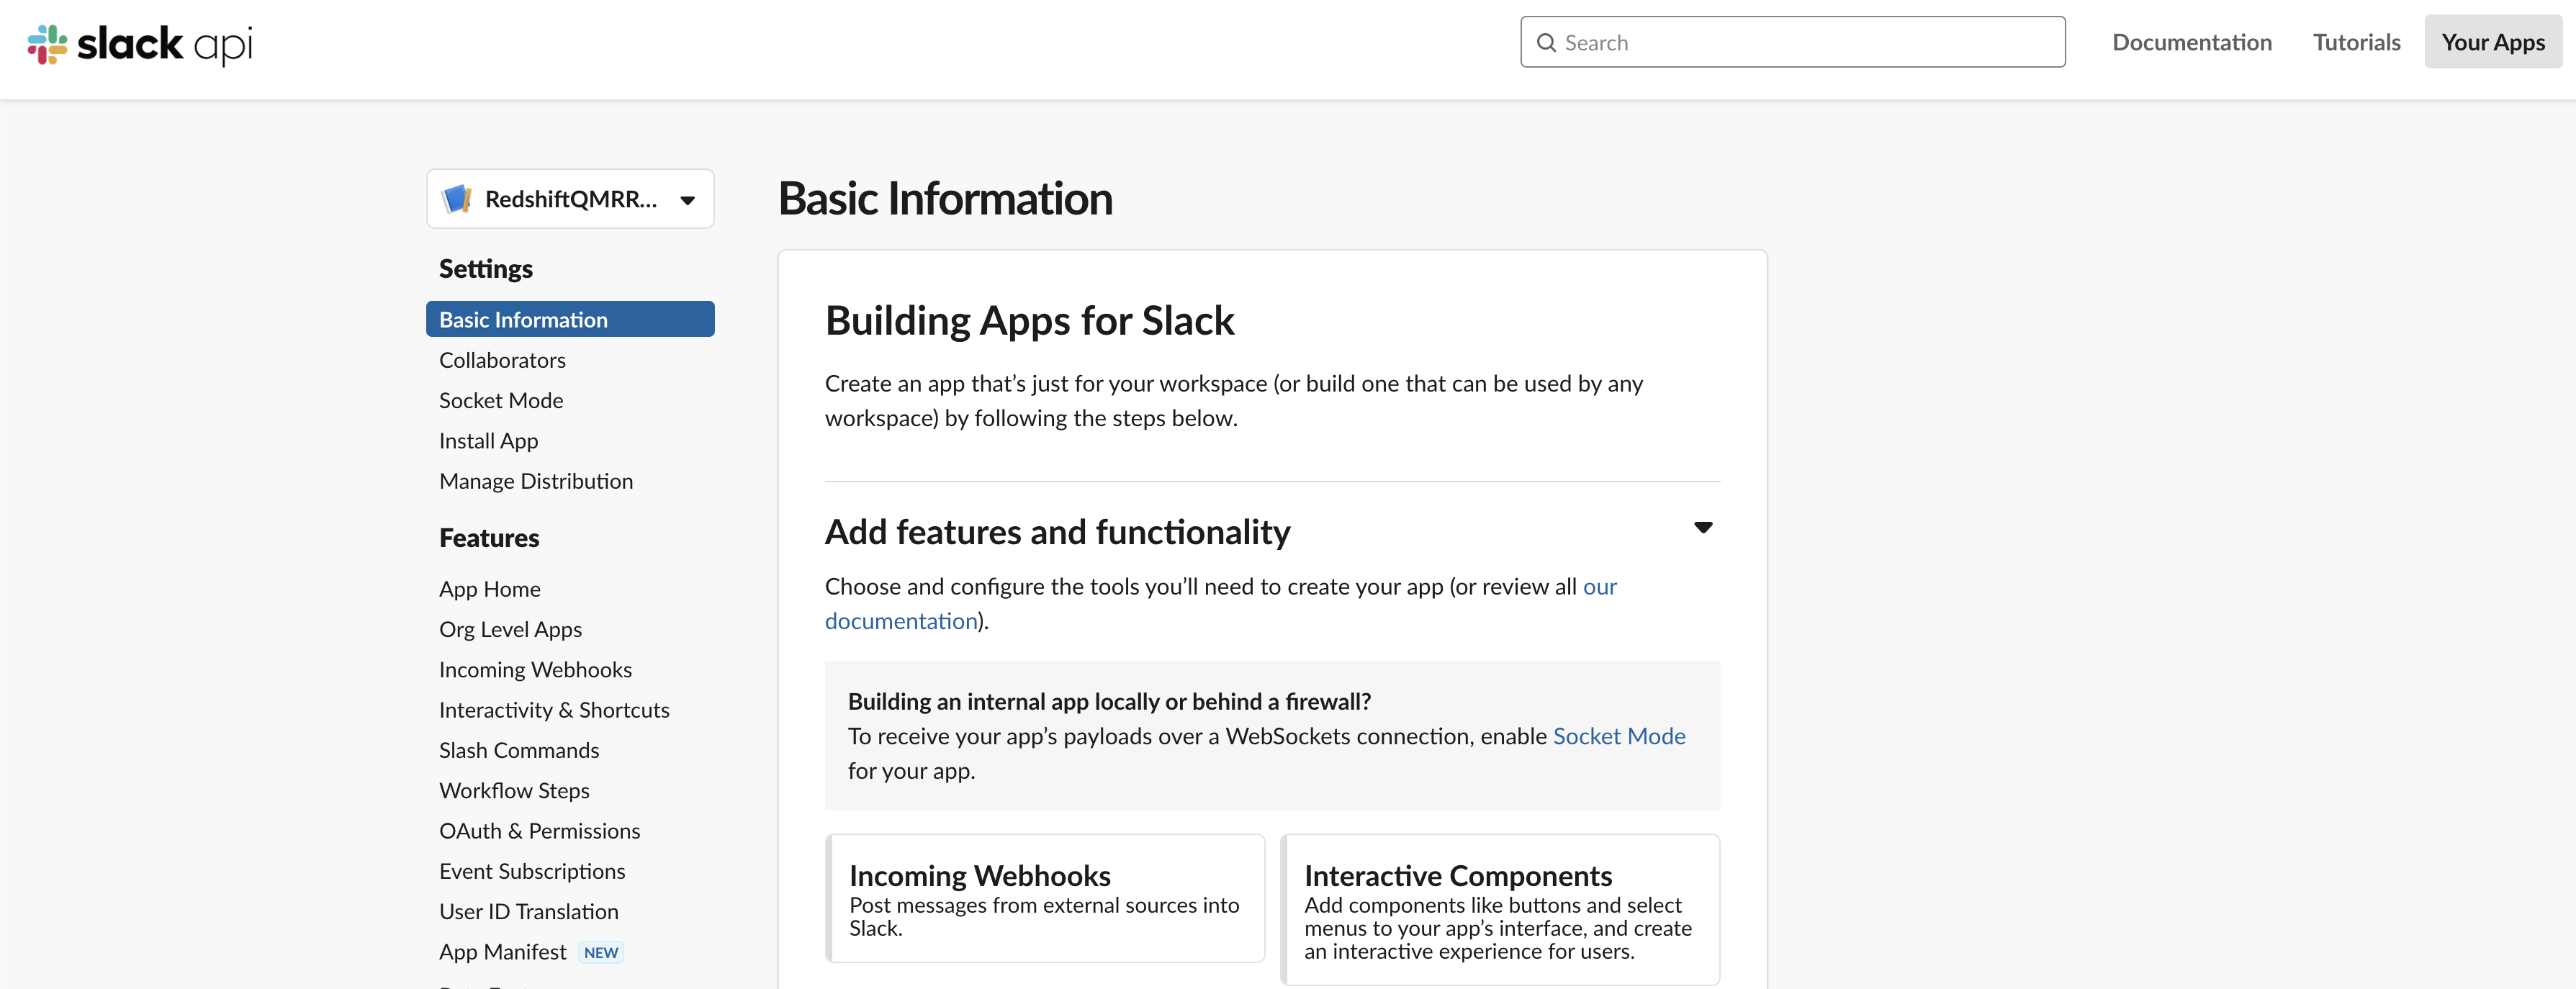
  1. In the Slack app, under Settings in the navigation pane, choose Basic Information.
  2. Choose Incoming Webhooks.
  3. Turn on Activate Incoming Webhooks.
  4. Choose Add New Webhook to Workspace.
  5. Authorize the Slack app RedshiftQMRRuleNotification so that it can post messages to the private Slack channel redshift-qmr-notification-*****-*******.

The following screenshot shows the details of the newly added incoming webhook.

Create a second Lambda function and subscribe to the SNS topic

In this step, you create a second Lambda function that is subscribed to the SNS topic that you created earlier. For full instructions, refer to Building Lambda functions with Python and Subscribing a function to a topic.

For this post, we create a second function named redshiftqmrrulesnsinvoke, which is subscribed to the SNS topic redshiftqmrrulenotification. The second function sends a detailed QMR violation message (received from the SNS topic) to the designated Slack channel named redshift-qmr-notification-*. This function uses the incoming Slack webhook that we created earlier.

We also create an SNS subscription of the second Lambda function to the SNS topic that we created previously.

The following is the Python 3.9 code used for the second Lambda function:

import urllib3
import json
import os

http = urllib3.PoolManager()
def lambda_handler(event, context):
    
    url = os.environ['webhook']
    channel = os.environ['channel']
    msg = {
        "channel": channel,
        "username": "WEBHOOK_USERNAME",
        "text": event['Records'][0]['Sns']['Message'],
        "icon_emoji": ""
    }
    
    encoded_msg = json.dumps(msg).encode('utf-8')
    resp = http.request('POST',url, body=encoded_msg)
    print({
        "message": event['Records'][0]['Sns']['Message'], 
        "status_code": resp.status, 
        "response": resp.data
    })

We use two environment variables for the second Lambda function:

  • channel – The Slack channel that we created
  • webhook – The Slack webhook that we created

Test the solution

To show the effect of the QMRs, we ran queries that violate the QMRs we set up.

Test 1: Returned rows

Test 1 looks for violations of the returned_rows QMR, in which the return row count is over 1,000,000 for a query that ran in the adhoc queue.

We created and loaded a table named lineitem in a schema named aquademo, which has more than 18 billion records. You can refer to the GitHub repo to create and load the table.

We ran the following query, which violated the returned_rows QMR, and the query was stopped as specified in the action set in the QMR.

select * from aquademo.lineitem limit 1000001;

The following screenshot shows the view from the Amazon Redshift client after running the query.

The following screenshot shows the view on the Amazon Redshift console.

The following screenshot shows the notification we received in our Slack channel.

Test 2: Long-running queries

Test 2 looks for violations of the long_running QMR, in which query runtime is over 300 seconds for a user who belongs to reporting_group.

In the following code, we created a new Amazon Redshift group named reporting_group and added a new user, named reporting_user, to the group. reporting_group is assigned USAGE and SELECT privileges on all tables in the retail and aquademo schemas.

create group reporting_group;
create user reporting_user in group reporting_group password 'Test12345';
grant usage on schema retail,aquademo to group reporting_group;
grant select on all tables in schema retail,aquademo to group reporting_group;

We set the session authorization to reporting_user so the query runs in the reporting queue. We ran the following query, which violated the long_running QMR, and the query was stopped as specified in the action set in the QMR:

set session authorization reporting_user;
set enable_result_cache_for_session  to off;
select * from aquademo.lineitem;

The following screenshot shows the view from the Amazon Redshift client.

The following screenshot shows the view on the Amazon Redshift console.

The following screenshot shows the notification we received in our Slack channel.

Test 3: Nested loops

Test 3 looks for violations of the nested_loop QMR, in which the nested loop join row count is over 10,000,000 for a user who belongs to reporting_group.

We set the session authorization to reporting_user so the query runs in the reporting queue. We ran the following query, which violated the nested_loop QMR, and the query logged the violation as specified in the action set in the QMR:

set session authorization reporting_user;
set enable_result_cache_for_session  to off;
select ss.*,cd.* 
from retail.store_sales ss
, retail.customer_demographics cd;

Before we ran the original query, we also checked the explain plan and noted that this nested loop will return more than 10,000,000 rows. The following screenshot shows the query explain plan.

The following screenshot shows the notification we received in our Slack channel.

Test 4: Redshift Spectrum scans

Test 4 looks for violations of the spectrum_scan QMR, in which Redshift Spectrum scans exceed 1000 MB for a query that ran in the adhoc queue.

For this example, we used store_sales data (unloaded from an Amazon Redshift table that was created by using the TPC-DS benchmark data) loaded in an Amazon S3 location. Data in Amazon S3 is non-partitioned under one prefix and has a volume around 3.9 GB. We created an external schema (qmr_spectrum_rule_test) and external table (qmr_rule_store_sales) in Redshift Spectrum.

We used the following steps to run this test with the sample data:

  1. Run an unload SQL command:
    unload ('select * from store_sales')
    to 's3://<<Your Amazon S3 Location>>/store_sales/' 
    iam_role default;

  2. Create an external schema from Redshift Spectrum:
    CREATE EXTERNAL SCHEMA if not exists qmr_spectrum_rule_test
    FROM DATA CATALOG DATABASE 'qmr_spectrum_rule_test' region 'us-east-1' 
    IAM_ROLE default
    CREATE EXTERNAL DATABASE IF NOT exists;

  3. Create an external table in Redshift Spectrum:
    create external table qmr_spectrum_rule_test.qmr_rule_store_sales
    (
    ss_sold_date_sk int4 ,            
      ss_sold_time_sk int4 ,     
      ss_item_sk int4  ,      
      ss_customer_sk int4 ,           
      ss_cdemo_sk int4 ,              
      ss_hdemo_sk int4 ,         
      ss_addr_sk int4 ,               
      ss_store_sk int4 ,           
      ss_promo_sk int4 ,           
      ss_ticket_number int8 ,        
      ss_quantity int4 ,           
      ss_wholesale_cost numeric(7,2) ,          
      ss_list_price numeric(7,2) ,              
      ss_sales_price numeric(7,2) ,
      ss_ext_discount_amt numeric(7,2) ,             
      ss_ext_sales_price numeric(7,2) ,              
      ss_ext_wholesale_cost numeric(7,2) ,           
      ss_ext_list_price numeric(7,2) ,               
      ss_ext_tax numeric(7,2) ,                 
      ss_coupon_amt numeric(7,2) , 
      ss_net_paid numeric(7,2) ,   
      ss_net_paid_inc_tax numeric(7,2) ,             
      ss_net_profit numeric(7,2)                     
    ) ROW FORMAT DELIMITED 
      FIELDS TERMINATED BY '|' 
    STORED AS INPUTFORMAT 
      'org.apache.hadoop.mapred.TextInputFormat' 
    OUTPUTFORMAT 
      'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
    LOCATION
      's3://<<Your Amazon S3 Location>>/store_sales/'
    TABLE PROPERTIES (
      'averageRecordSize'='130', 
      'classification'='csv', 
      'columnsOrdered'='true', 
      'compressionType'='none', 
      'delimiter'='|', 
      'recordCount'='11083990573', 
      'sizeKey'='1650877678933', 
      'typeOfData'='file');

  4. Run the following query:
    select * 
    FROM qmr_spectrum_rule_test.qmr_rule_store_sales 
    where ss_sold_date_sk = 2451074;

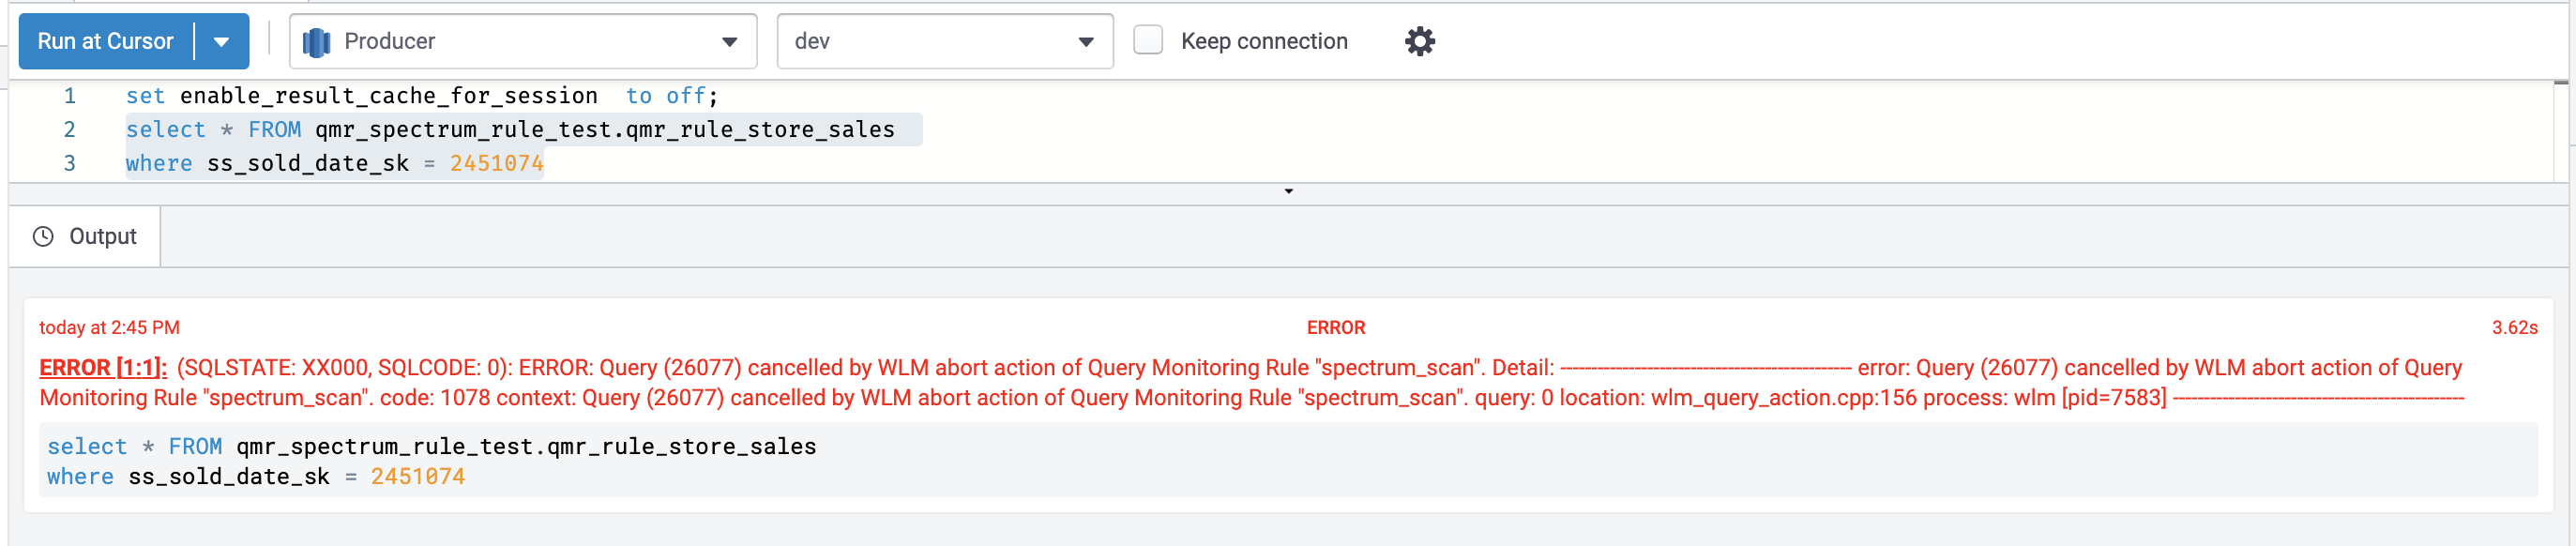
The query violated the spectrum_scan QMR, and the query was stopped as specified in the action set in the QMR.

The following screenshot shows the view from the Amazon Redshift client.

The following screenshot shows the view on the Amazon Redshift console.

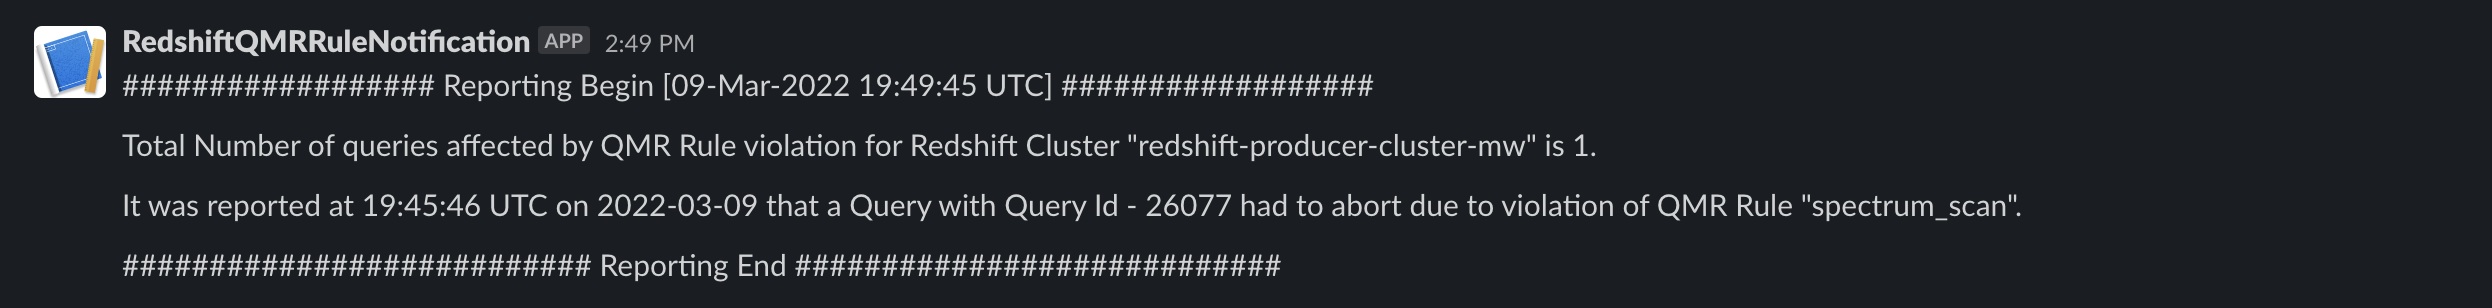
The following screenshot shows the notification we received in our Slack channel.

Clean up

When you’re finished with this solution, we recommend deleting the resources you created to avoid incurring any further charges.

Conclusion

Amazon Redshift is a powerful, fully managed data warehouse that can offer significantly increased performance and lower cost in the cloud. In this post, we discussed how you can automate notification of misbehaving queries on Slack by using query monitoring rules. QMRs can help you maximize cluster performance and throughput when supporting mixed workloads. Use these instructions to set up your Slack channel to receive automatic notifications from your Amazon Redshift cluster for any violation of QMRs.


About the Authors

Dipankar Kushari is a Senior Specialist Solutions Architect in the Analytics team at AWS.

Harshida Patel is a Specialist Senior Solutions Architect in the Analytics team at AWS.

Share data securely across Regions using Amazon Redshift data sharing

Post Syndicated from Rahul Chaturvedi original https://aws.amazon.com/blogs/big-data/share-data-securely-across-regions-using-amazon-redshift-data-sharing/

Today’s global, data-driven organizations treat data as an asset and use it across different lines of business (LOBs) to drive timely insights and better business decisions. This requires you to seamlessly share and consume live, consistent data as a single source of truth without copying the data, regardless of where LOB users are located.

Amazon Redshift is a fast, scalable, secure, and fully managed data warehouse that enables you to analyze all your data using standard SQL easily and cost-effectively. Amazon Redshift data sharing allows you to securely share live, transactionally consistent data in one Amazon Redshift cluster with another Amazon Redshift cluster across accounts and Regions, without needing to copy or move data from one cluster to the other.

Amazon Redshift data sharing was initially launched in March 2021, and support for cross-account data sharing was added in August 2021. Cross-Region support became generally available in February 2022. This provides full flexibility and agility to easily share data across Amazon Redshift clusters in the same AWS account, different accounts, or different Regions.

In this post, we discuss how to configure cross-Region data sharing between different accounts or in the same account.

Solution overview

It’s easy to set up cross-account and cross-Region data sharing from producer to consumer clusters, as shown in the following flow diagram. The workflow consists of the following components:

  • Producer cluster administrator – The producer admin is responsible for the following:
    • Create an Amazon Redshift database share (a new named object to serve as a unit of sharing, referred to as a datashare) on the AWS Management Console
    • Add database objects (schemas, tables, views) to the datashare
    • Specify a list of consumers that the objects should be shared with
  • Consumer cluster administrator – The consumer admin is responsible for the following:
    • Examine the datashares that are made available and review the content of each share
    • Create an Amazon Redshift database from the datashare object
    • Assign permissions on this database to appropriate users and group in the consumer cluster
  • Users and groups in the consumer cluster – Users and groups can perform the following actions:
    • List the shared objects as part of standard metadata queries
    • Start querying immediately

In the following sections, we discuss use cases and how to implement the cross-Region sharing feature between different accounts or in the same account.

Use cases

Common use cases for the data sharing feature include implementing multi-tenant patterns, data sharing for workload isolation, and security considerations related to data sharing.

In this post, we demonstrate cross-Region data sharing, which is especially useful for the following use cases:

  • Support for different kinds of business-critical workloads – You can use a central extract, transform, and load (ETL) cluster that shares data with multiple business intelligence (BI) or analytic clusters owned by geographically distributed business groups
  • Enabling cross-group collaboration – The solution enables seamless collaboration across teams and business groups for broader analytics, data science, and cross-product impact analysis
  • Delivering data as a service – You can share data as a service across your organization
  • Sharing data between environments – You can share data among development, test, and production environments at different levels of granularity
  • Licensing access to data in Amazon Redshift – You can publish Amazon Redshift datasets in the AWS Data Exchange that customers can find, subscribe to, and query in minutes.

Cross-Region data sharing between different accounts

In this use case, we share data from a cluster in an account in us-east-1 with a cluster owned by a different account in us-west-2. The following diagram illustrates this architecture.

When setting up cross-Region data sharing across different AWS accounts, there’s an additional step to authorize a datashare on the producer account and associate the datashare on the consumer account. The reason is that for such shares that go outside of your account or organization, you must have a two-step authentication process. For example, consider a scenario where the database analyst creates a database share using the console and now requires the producer administrator to authorize this datashare. For same-account sharing, we don’t require that two-step approach because you’re granting access within the perimeter of your own account.

This setup broadly follows a four-step process:

  1. Create a datashare on the producer account.
  2. Authorize the datashare on the producer account.
  3. Associate the datashare on the consumer account.
  4. Query the datashare.

Create a datashare

To create your datashare, complete the following steps:

  1. On the Amazon Redshift console, create a producer cluster with encryption enabled.

This is in your source account. For instructions on how to automate process of creating an Amazon Redshift cluster, refer to Automate building an integrated analytics solution with AWS Analytics Automation Toolkit.

On the Datashares tab, no datashares are currently available on the producer account.

  1. Create a consumer cluster with encryption enabled in a different AWS account and different Region.

This is your target account. On the Datashares tab, no datashares are currently available on the consumer side.

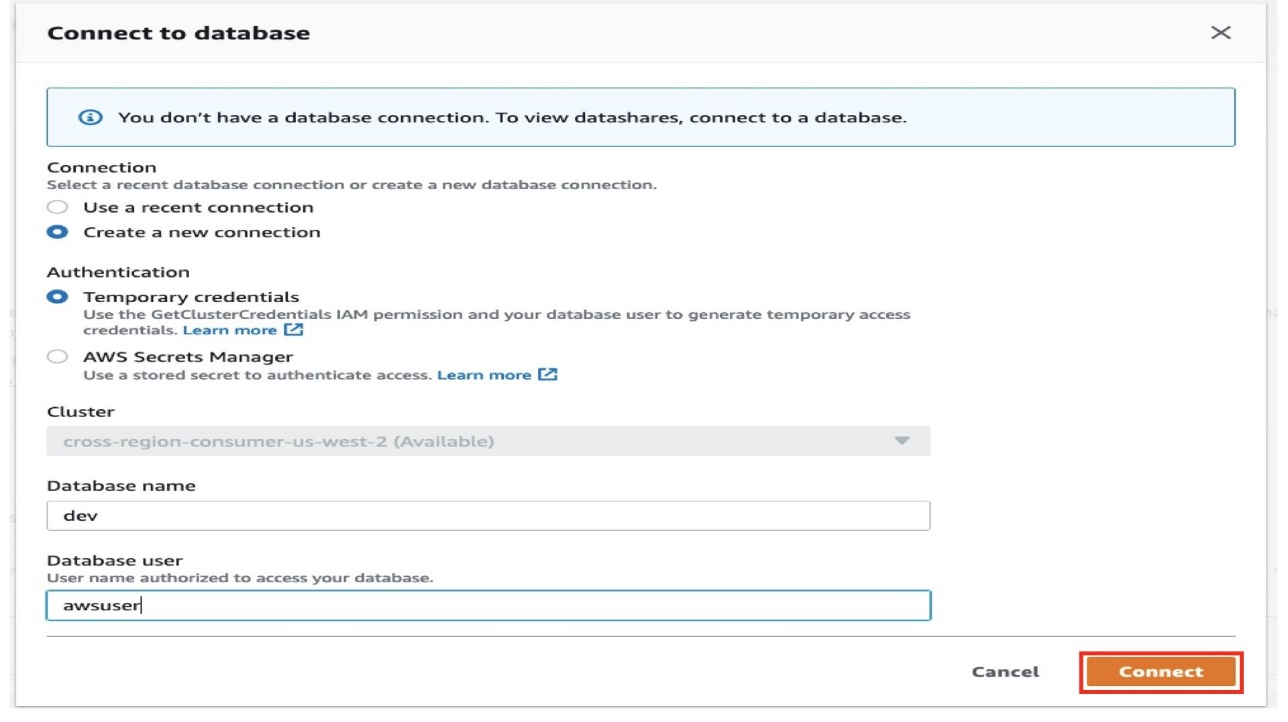
  1. Choose Connect to database to start setting up your datashare.
  2. For Connection, select Create a new connection.

You can connect to the database using either temporary credentials or AWS Secrets Manager. Refer to Querying a database using the query editor to learn more about these two connection options. We use temporary credentials in this post.

  1. For Authentication, select Temporary credentials.
  2. For Database name, enter a name (for this post, dev).
  3. For Database user, enter the user authorized to access the database (for this post, awsuser).
  4. Choose Connect.
  5. Repeat these steps on the producer cluster.
  6. Next, create a datashare on the producer.
  7. For Datashare type, select Datashare.
  8. For Database name, enter a name.
  9. For Database name, choose the database you specified earlier.
  10. For Publicly accessible, select Enable.
  11. In the Datashare objects section, choose Add to add the database schemas and tables to share.\

In our case, we add all tables and views from the public schema to the datashare.

  1. Choose Add.

Next, you add the consumer account in order to add a cross-account, cross-Region consumer to this datashare.

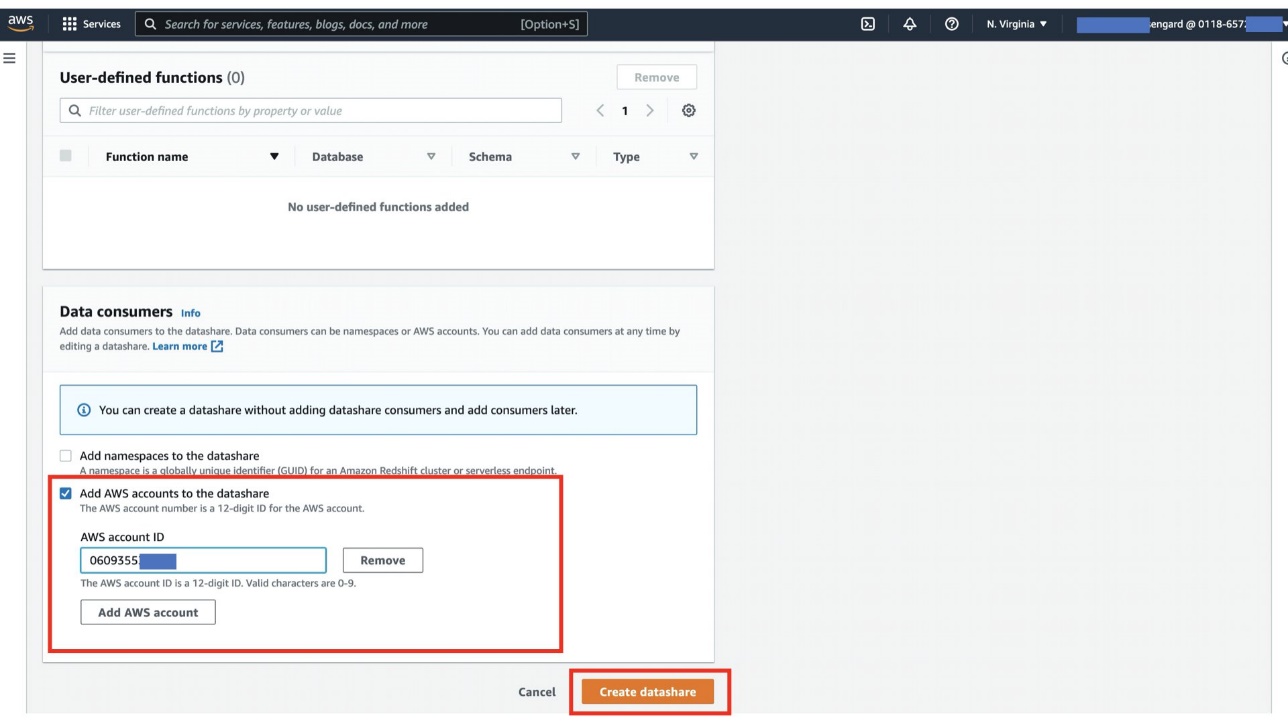
  1. In the Data consumers section, select Add AWS accounts to the datashare and enter your AWS account ID.
  2. Choose Create datashare.

Authorize the datashare

To authorize this datashare, complete the following steps:

  1. On the Amazon Redshift console, choose Datashares in the navigation pane.
  2. Choose the datashare you created earlier.
  3. In the Data consumers section, select the data consumer ID and choose Authorize.
  4. Choose Authorize to confirm.

Associate the datashare

On the consumer account in a different Region, we have multiple clusters. In this step, the consumer administrator associates this datashare to only to one of those clusters. As a consumer, you have the option to accept or decline a datashare. We associate this datashare to cross-region-us-west-2-team-a.

  1. On the Datashares page, choose the From other accounts tab to find the database you created in the source account.
  2. Select the appropriate datashare and choose Associate.

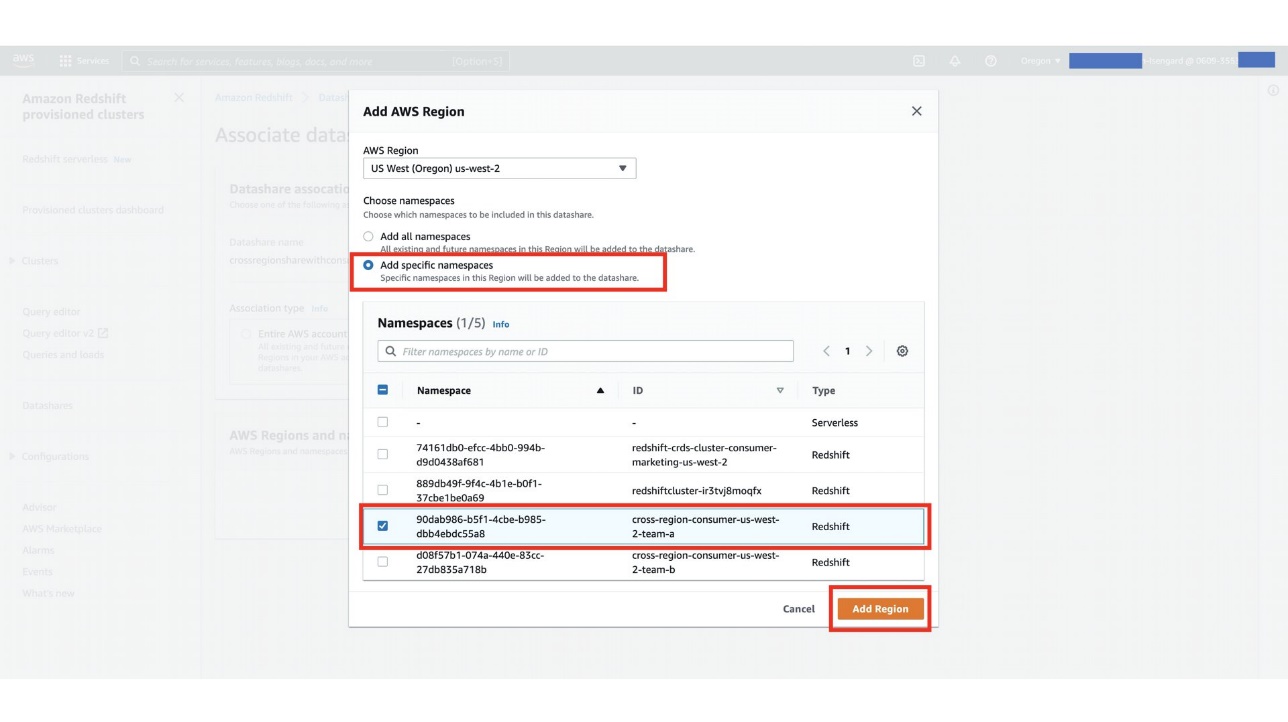
In the next step, you as a consumer admin have the option to associate the datashare with specific clusters in a different Region. Each cluster has its own globally unique identifier, known as a namespace. For this post, we associate the datashare to cluster cross-region-us-west-2-team-a with the namespace 90dab986-b5f1-4cbe-b985-dbb4ebdc55a8 in the us-west-2 Region.

  1. For Choose namespaces, select Add specific namespaces.
  2. Select your namespace and choose Add Region.
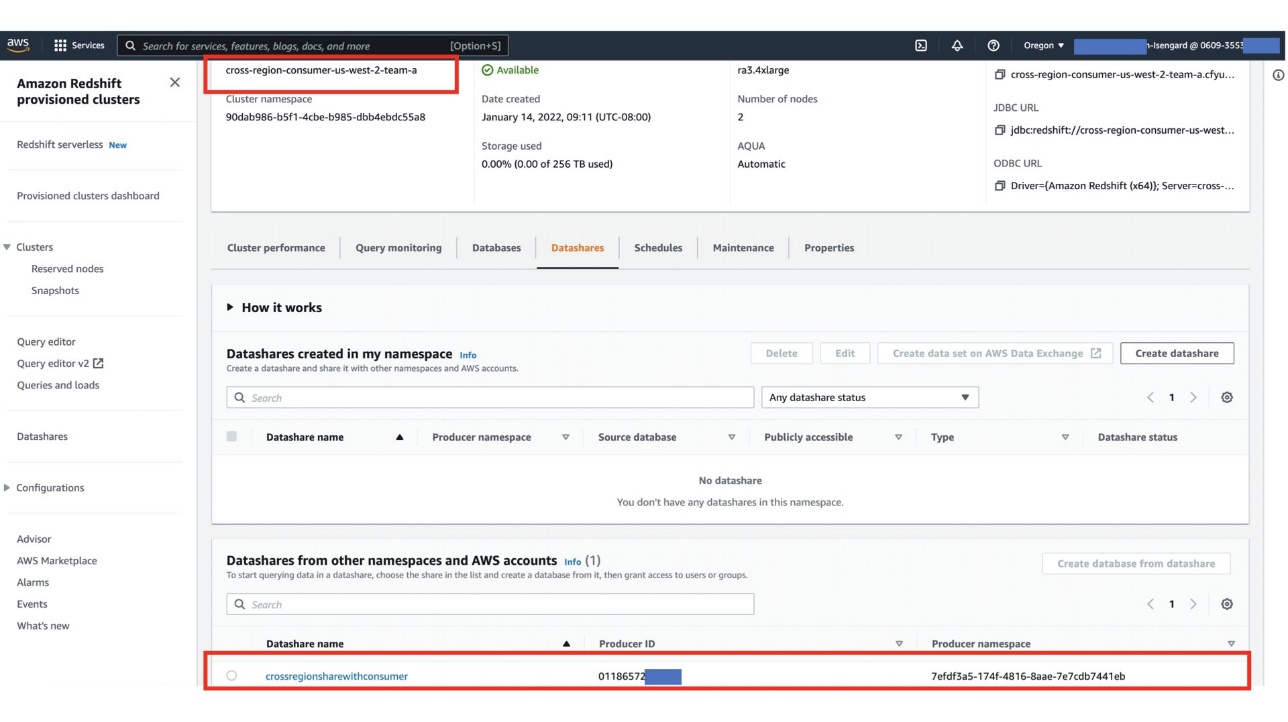
  3. Choose Clusters in the navigation pane.
  4. Choose the cluster that you authorized access to the datashare.
  5. On the Datashares tab, confirm the datashare from the producer cluster is listed in the Datashares from other namespaces and AWS accounts section.

Query the datashare

You can query shared data using standard SQL interfaces, JDBC or ODBC drivers, and the Data API. You can also query data with high performance from familiar BI and analytic tools. You can run queries by referring to the objects from other Amazon Redshift databases that are both local to and remote from your cluster that you have permission to access.

You can do so simply by staying connected to local databases in your cluster. Then you can create consumer databases from datashares to consume shared data.

After you have done so, you can run cross-database queries joining the datasets. You can query objects in consumer databases using the three-part notation consumer_database_name.schema_name.table_name. You can also query using external schema links to schemas in the consumer database. You can query both local data and data shared from other clusters within the same query. Such a query can reference objects from the current connected database and from other non-connected databases, including consumer databases created from datashares.

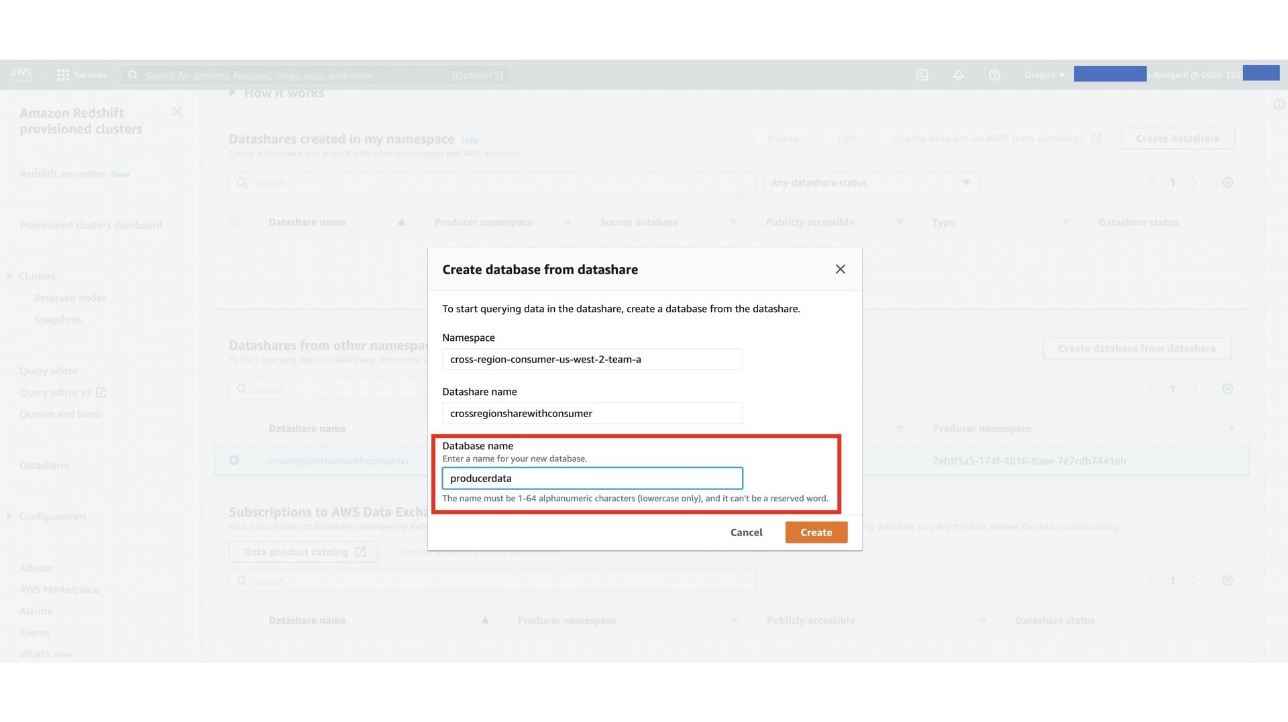
  1. On the consumer cluster, create a database to map the datashare objects to your cluster.
  2. You can now join your local schema objects with the objects in the shared database in a single query.

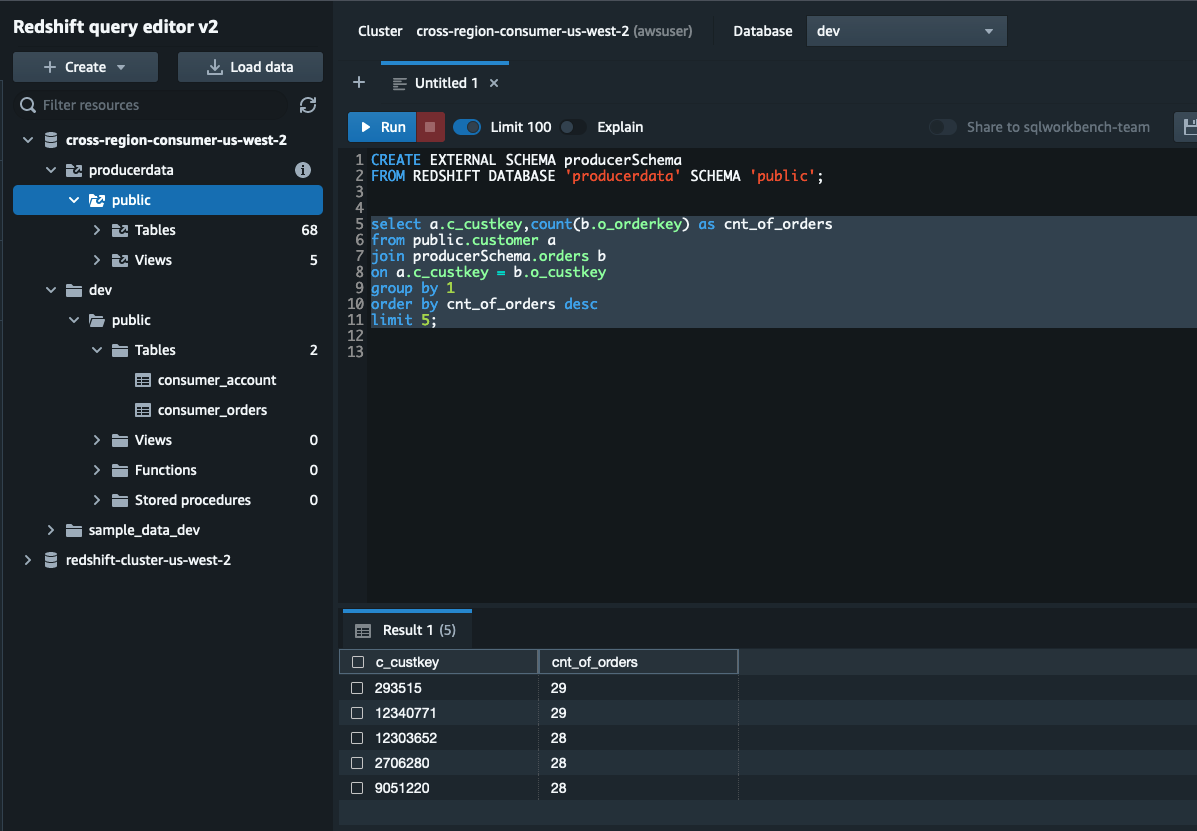
You can access the shared objects using a three-part notation, as highlighted in the following query:

select a.c_custkey,count(b.o_orderkey) as cnt_of_orders
from dev.public.customer a
join producerdata.public.orders b
on a.c_custkey = b.o_custkey
group by 1
order by cnt_of_orders desc 
limit 5;

The following screenshot shows our query results.

One alternative to using three-part notation is to create external schemas for the shared objects. As shown in the following code, we create producerSchema to map the datashare schema to a local schema:

Create external schema producerSchema
From REDSHIFT DATABASE ‘producerdata’ schema ‘public’;

Cross-Region data sharing in the same account

When setting up cross-Region data sharing in the same account, we don’t need to follow the authorize-associate flow on the console. We can easily configure this share using SQL commands. Complete the following steps:

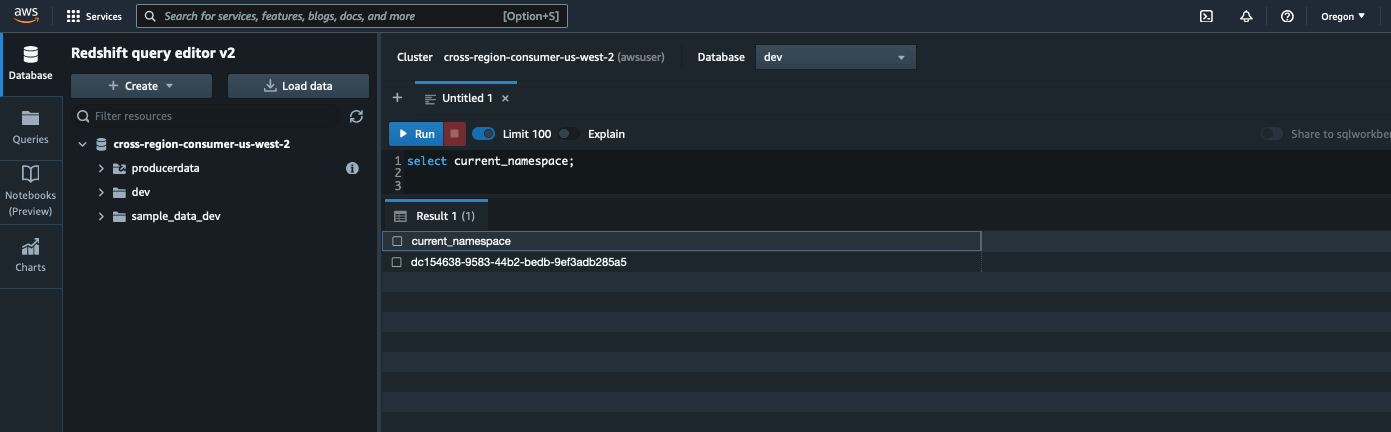
  1. On the consumer cluster, run the following SQL statement to get the current namespace:
    select current_namespace;

The following screenshot shows our results.

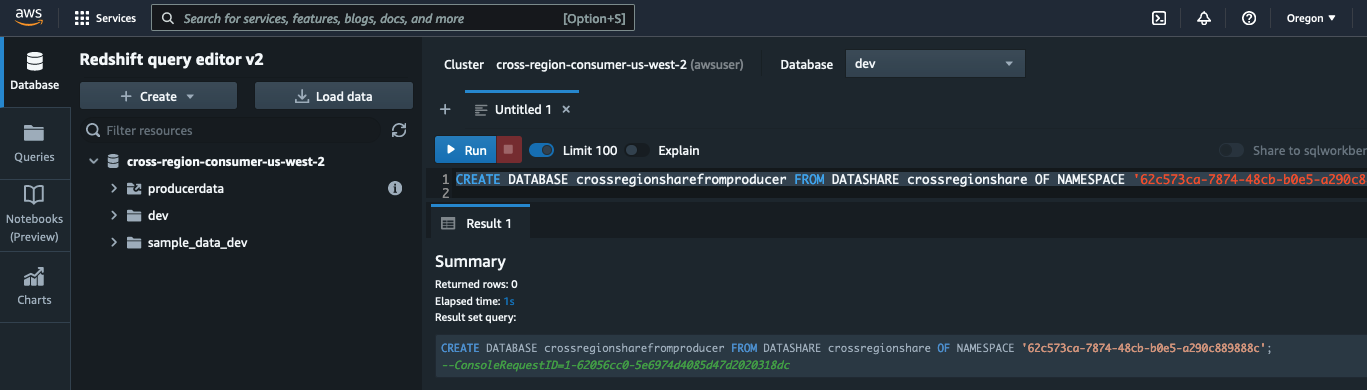
  1. On the producer cluster, run the SQL commands as shown in the following screenshot.

This step involves creating a datashare and making it publicly accessible so that the consumer can access it from across the Region. It then adds the database objects to the datashare, followed by granting permissions on this datashare to the consumer namespace. Use your consumer namespace from the previous step.

  1. Capture the producer namespace from the producer cluster to use in the next step.

The consumer cluster now has access to the datashare that was created on the producer.

  1. You can verify this from svv_datashares.
  2. After you confirm that the datashare is available on consumer, the next step is to map the objects of the datashare to a database in order to start querying them, as shown in the following screenshots.

Considerations for using cross-Region data sharing

Keep in mind the following when using cross-Region data sharing:

  • You must enable encryption both the producer and consumer accounts.
  • For cross-Region data sharing, the consumer pays the cross-Region data transfer fee from the producer Region to the consumer Region based on the price of Amazon Simple Storage Service (Amazon S3), in addition to the cost of using the Amazon Redshift cluster.
  • You can’t share stored procedures and Python UDF functions.
  • This feature is only supported on the RA3 instance type.
  • The producer cluster administrator is responsible for implementing any Region locality and compliance requirements (such as GDPR) by performing the following actions:
    • Share only data that can be shared outside a Region in a datashare.
    • Authorize the appropriate data consumer to access the datashare.
  • The performance of the queries on data shared across Regions depends on the compute capacity of the consumer clusters.
  • Network throughput between different Regions could yield different query performance. For instance, data sharing from us-east-1 to us-east-2 could yield better performance compared to us-east-1 to ap-northeast-1.

Summary

Amazon Redshift cross-Region data sharing is now available. Previously, data sharing was only allowed within the same Region. With this launch, you can share data across Regions with clusters residing in the same account or different accounts.

We look forward to hearing from you about your experience. If you have questions or suggestions, please leave a comment.


About the Authors

Rahul Chaturvedi is an Analytics Specialist Solutions Architect AWS. Prior to this role, he was a Data Engineer at Amazon Advertising and Prime Video, where he helped build petabyte-scale data lakes for self-serve analytics.

Kishore Arora is a Sr Analytics Specialist Solutions Architect at AWS. In this role, he helps customers modernize their data platform and architect big data solutions with AWS purpose-built data services. Prior to this role, he was a big data architect and delivery lead working with Tier-1 telecom customers.

BP Yau is a Sr Product Manager at AWS. He is passionate about helping customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.

Srikanth Sopirala is a Principal Analytics Specialist Solutions Architect at AWS. He is a seasoned leader with over 20 years of experience, who is passionate about helping customers build scalable data and analytics solutions to gain timely insights and make critical business decisions. In his spare time, he enjoys reading, spending time with his family, and road cycling.

Accelerate Snowflake to Amazon Redshift migration using AWS Schema Conversion Tool

Post Syndicated from BP Yau original https://aws.amazon.com/blogs/big-data/accelerate-snowflake-to-amazon-redshift-migration-using-aws-schema-conversion-tool/

Amazon Redshift is a fully managed, petabyte-scale data warehouse service in the cloud. You can start with just a few hundred gigabytes of data and scale to a petabyte or more. This enables you to use your data to acquire new insights for your business and customers. Today, tens of thousands of AWS customers—from Fortune 500 companies, startups, and everything in between—use Amazon Redshift to run mission-critical business intelligence (BI) dashboards, analyze real-time streaming data, and run predictive analytics jobs. With the constant increase in generated data, Amazon Redshift customers continue to achieve successes in delivering better service to their end-users, improving their products, and running an efficient and effective business.

Several new features of Amazon Redshift address a wide range of analytics requirements and improve performance of the cloud data warehouse:

To take advantage of these capabilities and future innovations, you must migrate from your existing data warehouse to Amazon Redshift.

In this post, we show you how to migrate your data warehouse schema from Snowflake to Amazon Redshift using AWS Schema Conversion Tool (AWS SCT). AWS SCT is a service that makes heterogeneous database migrations predictable by automatically converting the source database schema and a majority of the database code objects, including views, stored procedures, and functions, to a format compatible with the target database. Any objects that can’t be automatically converted are clearly marked so that they can be manually converted to complete the migration. AWS SCT can also scan your application source code for embedded SQL statements and convert them as part of a database schema conversion project. During this process, AWS SCT performs cloud-native code optimization by converting legacy data warehouse functions to their equivalent AWS service, thereby helping you modernize the applications at the same time of database migration.

Solution overview

To implement this solution, you complete the following high-level steps:

  1. Configure your AWS SCT application.
  2. Analyze your source Snowflake schema.
  3. Convert your Snowflake schema to an Amazon Redshift schema.
  4. Deploy the schema to Amazon Redshift.

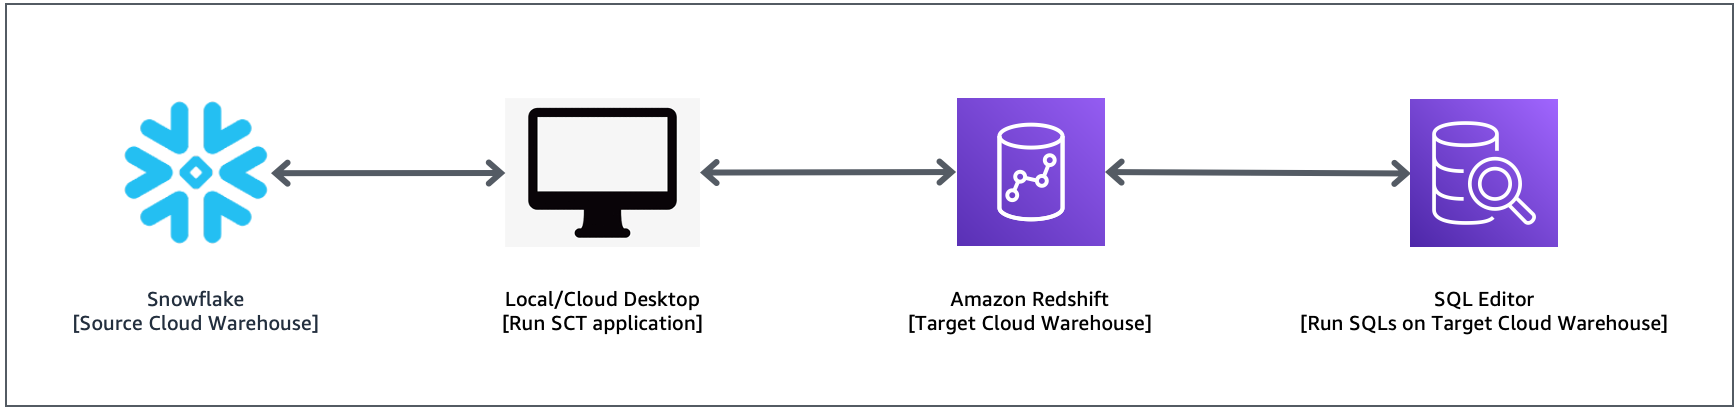
The following diagram illustrates the solution architecture.

Prerequisites

Before starting this walkthrough, you must have the following prerequisites:

Set up an AWS SCT project and extract the schema from the source

In this walkthrough, we use the Snowflake sample database TPCDS_SF10TCL as the source of the schema conversion.

To set up the database migration project, complete the following steps:

  1. Launch the AWS SCT application.
  2. On the File menu, choose New project wizard.
  3. Enter the project name and location.
  4. For Source engine, choose Snowflake.
  5. Choose Next.
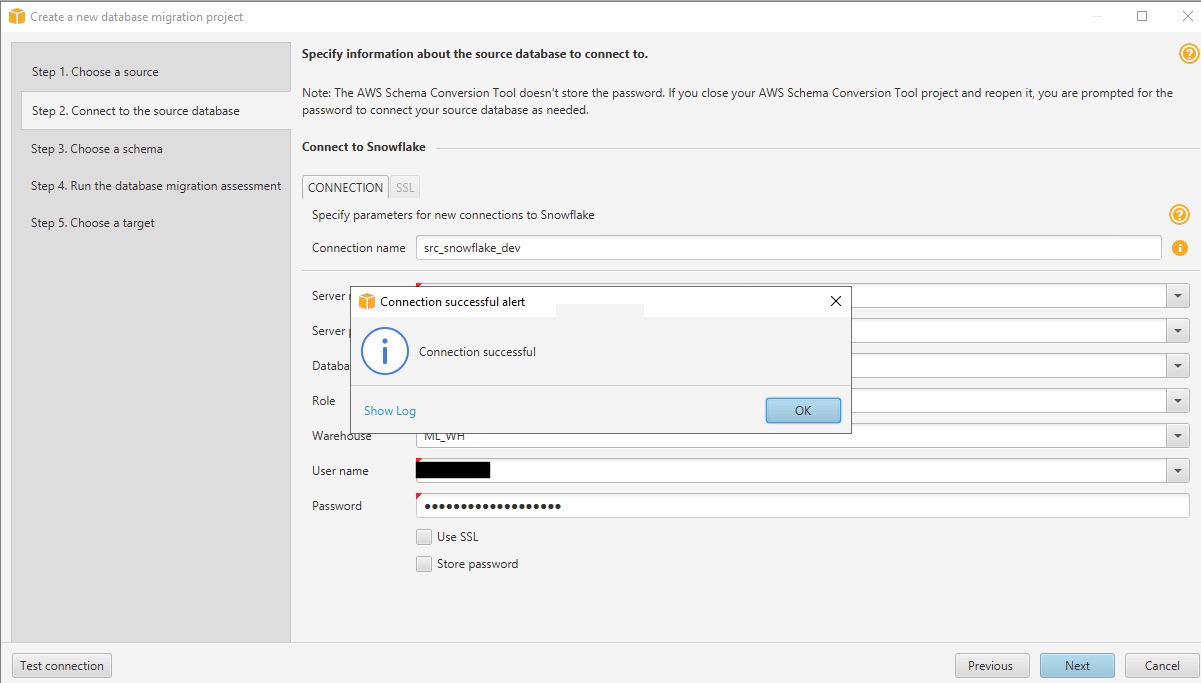
  6. Provide the database information and credentials for Snowflake and choose Test Connection.
  7. When the connection is successful, choose Next.

For more information, see Using Snowflake as a source for AWS SCT.

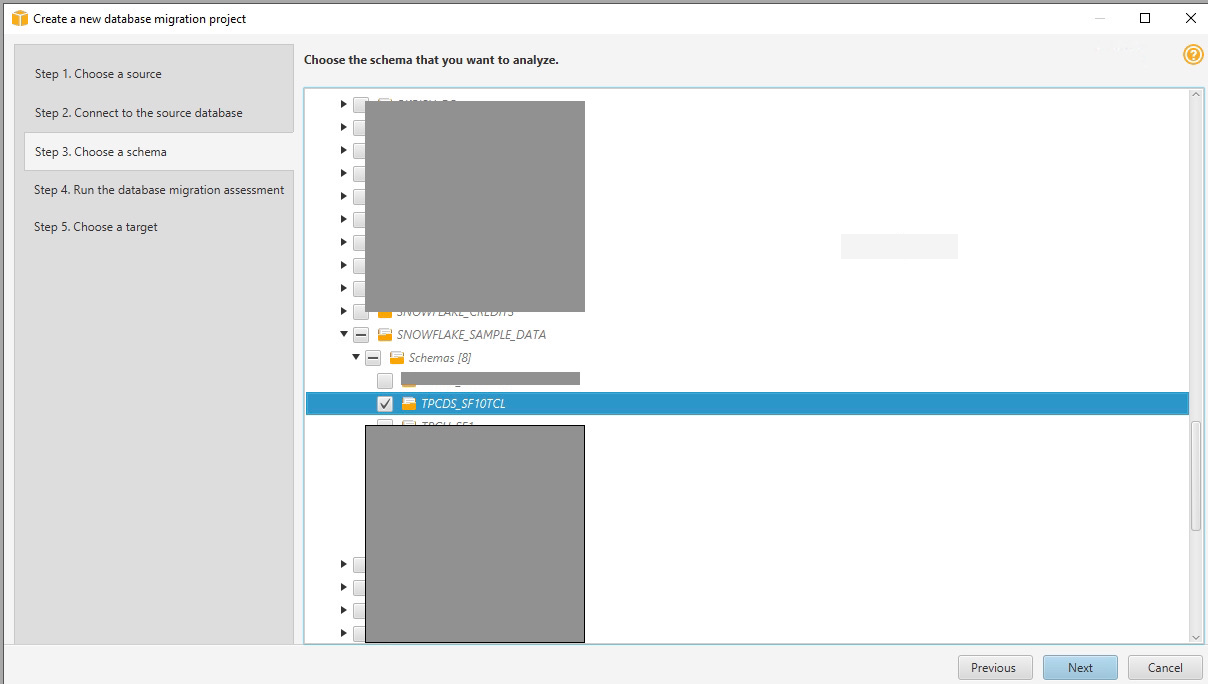
  1. Expand SNOWFLAKE_SAMPLE_DATA and Schemas.
  2. Select TPCDS_SF10TCL and choose Next.

AWS SCT analyzes the schema and prepares an assessment report summary, as shown in the following screenshot.

This report summarizes the objects that AWS SCT converts to Amazon Redshift.

  1. Review the report and choose Next.
  2. Provide the database information and credentials for Amazon Redshift and deselect Use AWS Glue.
  3. Choose Test Connection.
  4. When the connection is successful, choose Finish.

For more information about establishing a connection to Amazon Redshift, see Getting the JDBC URL.

Review and apply the schema from Snowflake to Amazon Redshift

To convert the schema from Snowflake objects to Amazon Redshift, complete the following steps:

  1. Expand SNOWFLAKE_SAMPLE_DATA and Schemas.
  2. Choose (right-click) TPCDS_SF10TCL and choose Convert schema.
  3. Choose Collect and continue.

AWS SCT converts the schema and shows the converted schema and objects in the right pane. The converted schema is marked with a red check mark.

Amazon Redshift take some actions automatically while converting the schema to Amazon Redshift; objects with such actions are marked with a red warning sign.

  1. Choose the object and then on the top menu, choose Main view and choose Assessment Report view.
  2. Choose the Action items tab.

You can see list of all issues and actions taken by AWS SCT.

You can evaluate and inspect the individual object DDL by selecting it from the right pane, and you can also edit it as needed. In the following example, we modify the DISTKEY to use inv_item_sk. AWS SCT analyze the tables and recommends the distribution and sort keys based on the statistics. For cases where you’re not sure, you should set it to AUTO. For more information about automatic data distribution and optimization in Amazon Redshift, refer to Automate your Amazon Redshift performance tuning with automatic table optimization.

  1. To deploy the objects DDL to Amazon Redshift, select the converted schema in the right pane, right-click, and choose Apply to database.
  2. Optionally, if you want to export the copy of the DDLs generated by AWS SCT and apply them manually, you can select the Amazon Redshift converted schema, right-click, and choose Save as SQL.
  3. Log in to your Amazon Redshift cluster using the Query Editor V2.

For more information about Query Editor V2, refer to Introducing Amazon Redshift Query Editor V2, a Free Web-based Query Authoring Tool for Data Analysts.

  1. To verify that the converted schema objects are deployed in Amazon Redshift, select the desired table, right-click, and choose Show table definition to see the underlying DDL.

Clean up

To avoid incurring future charges, complete the following steps:

  1. Delete the Amazon Redshift cluster created for this demonstration.
  2. If you were using an existing cluster, delete the new tables that you created as part of this exercise.
  3. Stop any Amazon Elastic Compute Cloud (Amazon EC2) instances that were created to run the AWS SCT application.

Summary

In this post, we showed how easy it is to convert a Snowflake schema to an Amazon Redshift schema and used AWS SCT for this automatic conversion.

We look forward to hearing from you about your experience. If you have questions or suggestions, please leave a comment.


About the Authors

BP Yau is a Sr Analytics Specialist Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.

Tahir Aziz is an Analytics Solution Architect at AWS. He has worked with building data warehouses and big data solutions for over 13 years. He loves to help customers design end-to-end analytics solutions on AWS. Outside of work, he enjoys traveling and cooking.

Shawn Sachdev is a Sr Analytics Specialist Solutions Architect at AWS. He works with customers and provides guidance to help them innovate and build well-architected and high-performance data warehouses and implement analytics at scale on the AWS platform. Before AWS, he has worked in several Analytics and System Engineering roles. Outside of work, he loves watching sports, and is an avid foodie and a craft beer enthusiast.

Srikanth Sopirala is a Principal Analytics Specialist Solutions Architect at AWS. He is a seasoned leader with over 20 years of experience, who is passionate about helping customers build scalable data and analytics solutions to gain timely insights and make critical business decisions. In his spare time, he enjoys reading, spending time with his family, and road cycling.

Integrate Amazon Redshift native IdP federation with Microsoft Azure AD using a SQL client

Post Syndicated from Maneesh Sharma original https://aws.amazon.com/blogs/big-data/integrate-amazon-redshift-native-idp-federation-with-microsoft-azure-ad-using-a-sql-client/

Amazon Redshift accelerates your time to insights with fast, easy, and secure cloud data warehousing at scale. Tens of thousands of customers rely on Amazon Redshift to analyze exabytes of data and run complex analytical queries.

The new Amazon Redshift native identity provider authentication simplifies administration by sharing identity and group membership information to Amazon Redshift from a third-party identity provider (IdP) service, such as Microsoft Azure Active Directory (Azure AD), and enabling Amazon Redshift to natively process third-party tokens, identities, and group permissions. This process is very easy to set up, provides a secure and smoother customer experience for managing identities and groups at a centralized external IdP, and integrates natively with Amazon Redshift.
In this post, we focus on Microsoft Azure AD as the IdP and provide step-by-step guidance to connect SQL clients like SQL Workbench/J and DBeaver with Amazon Redshift using a native IdP process. Azure AD manages the users and provides federated access to Amazon Redshift. You don’t need to create separate Amazon Redshift database users, AWS Identity and Access Management (IAM) roles, or IAM policies with this setup.

Solution overview

Using an Amazon Redshift native IdP has the following benefits:

  • Enables your users to be automatically signed in to Amazon Redshift with their Azure AD accounts
  • You can manage users and groups from a centralized IdP
  • External users can securely access Amazon Redshift without manually creating new user names or roles using their existing corporate directory credentials
  • External user group memberships are natively mirrored with Amazon Redshift roles and users

The following diagram illustrates the architecture of a native IdP for Amazon Redshift:

The workflow contains the following steps:

  1. You configure a JDBC or ODBC driver in your SQL client to use Azure AD federation and use Azure AD login credentials to sign in.
  2. Upon a successful authentication, Azure AD issues an authentication token (OAuth token) back to the Amazon Redshift driver.
  3. The driver forwards the authentication token to the Amazon Redshift cluster to initiate a new database session.
  4. Amazon Redshift verifies and validates the authentication token.
  5. Amazon Redshift calls the Azure Graph API to obtain the user’s group membership.
  6. Amazon Redshift maps the logged-in Azure AD user to the Amazon Redshift user and maps the Azure AD groups to Amazon Redshift roles. If the user and groups don’t exist, Amazon Redshift automatically creates those identities within the IdP namespace.

To implement the solution, you complete the following high-level steps:

  1. Set up your Azure application.
    1. Create OAuth Application
    2. Create Redshift Client application
    3. Create Azure AD Group
  2. Collect Azure AD information for the Amazon Redshift IdP.
  3. Set up the IdP on Amazon Redshift.
  4. Set up Amazon Redshift permissions to external identities.
  5. Configure the SQL client (for this post, we use SQL Workbench/J and DBeaver).

Prerequisites

You need the following prerequisites to set up this solution:

Set up your Azure application

For integrating with any SQL client/BI tool except Microsoft Power BI, we would be creating two applications. First application will be used to authenticate the user and provide a login token.  Second application will be used by Redshift to retrieve user and group information.

Step 1: Create OAuth Application

  1. Sign in to the Azure portal with your Microsoft account.
  2. Navigate to the Azure Active Directory application.
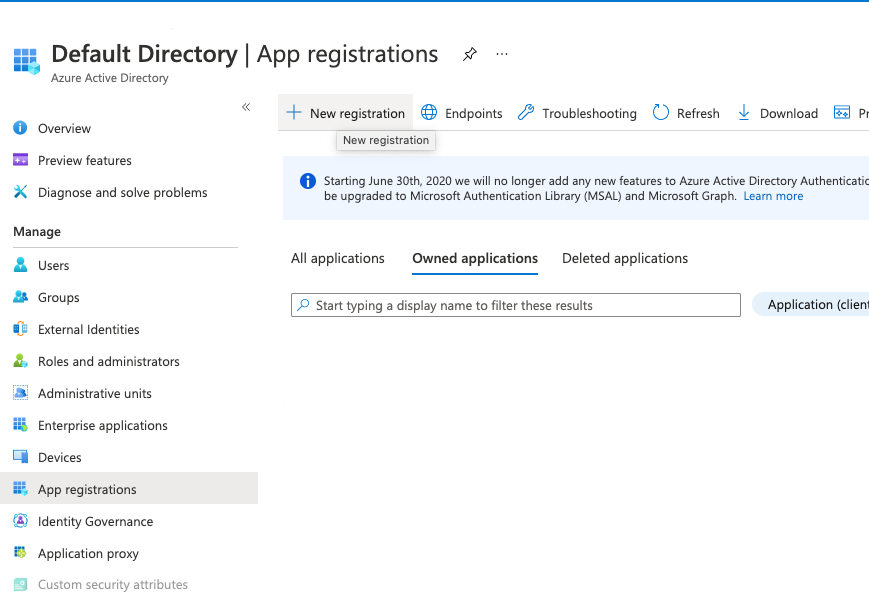
  3. Under Manage in the navigation pane, choose App registrations and then choose New registration.
  4. For Name, enter a name (for example, oauth_application).
  5. For Redirect URI, choose Public client/native (mobile and desktop) and enter the redirect URL http://localhost:7890/redshift/. For this post, we are keeping the default settings for the rest of the fields.
  6. Choose Register.
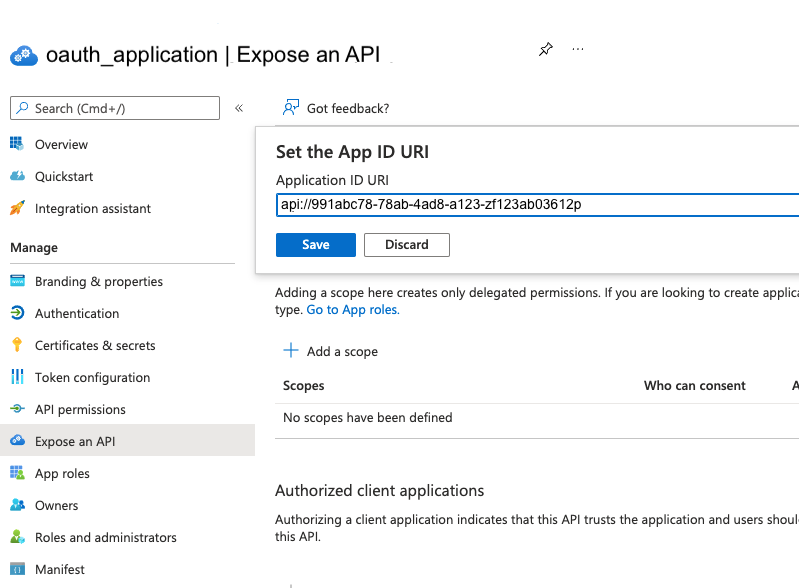
  7. In the navigation pane, under Manage, choose Expose an API.

If you’re setting up for the first time, you can see Set to the right of Application ID URI.

  1. Choose Set and then choose Save.
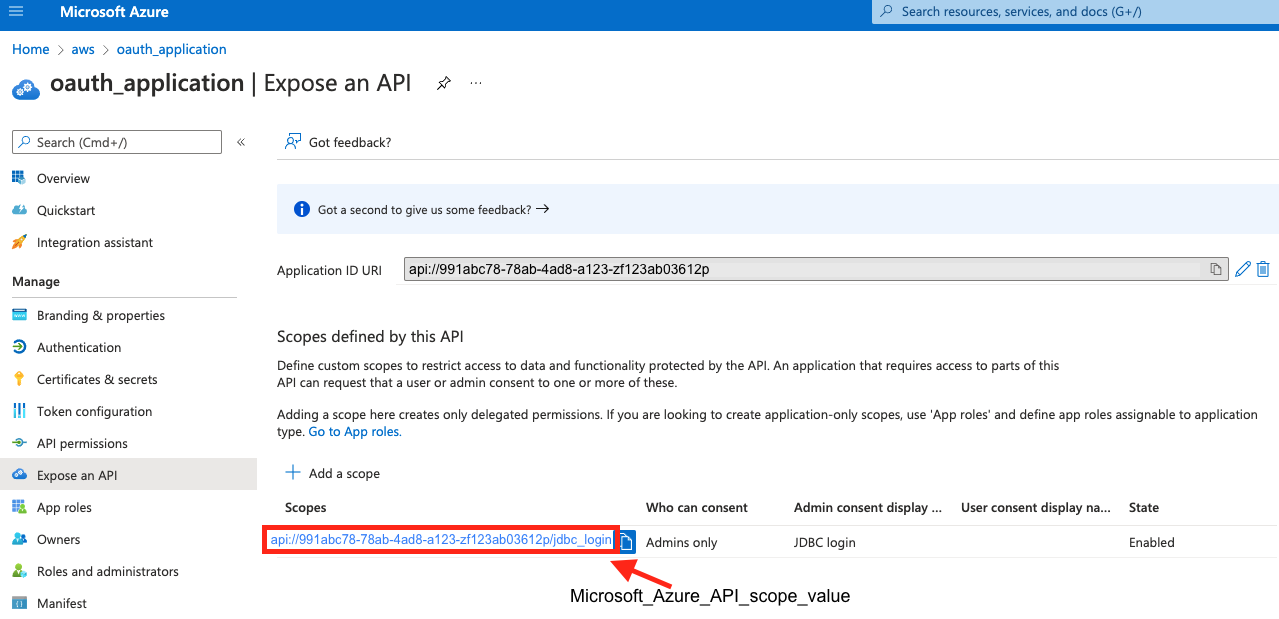
  2. After the application ID URI is set up, choose Add a scope.
  3. For Scope name, enter a name (for example, jdbc_login).
  4. For Admin consent display name, enter a display name (for example, JDBC login).
  5. For Admin consent description, enter a description of the scope.
  6. Choose Add scope.

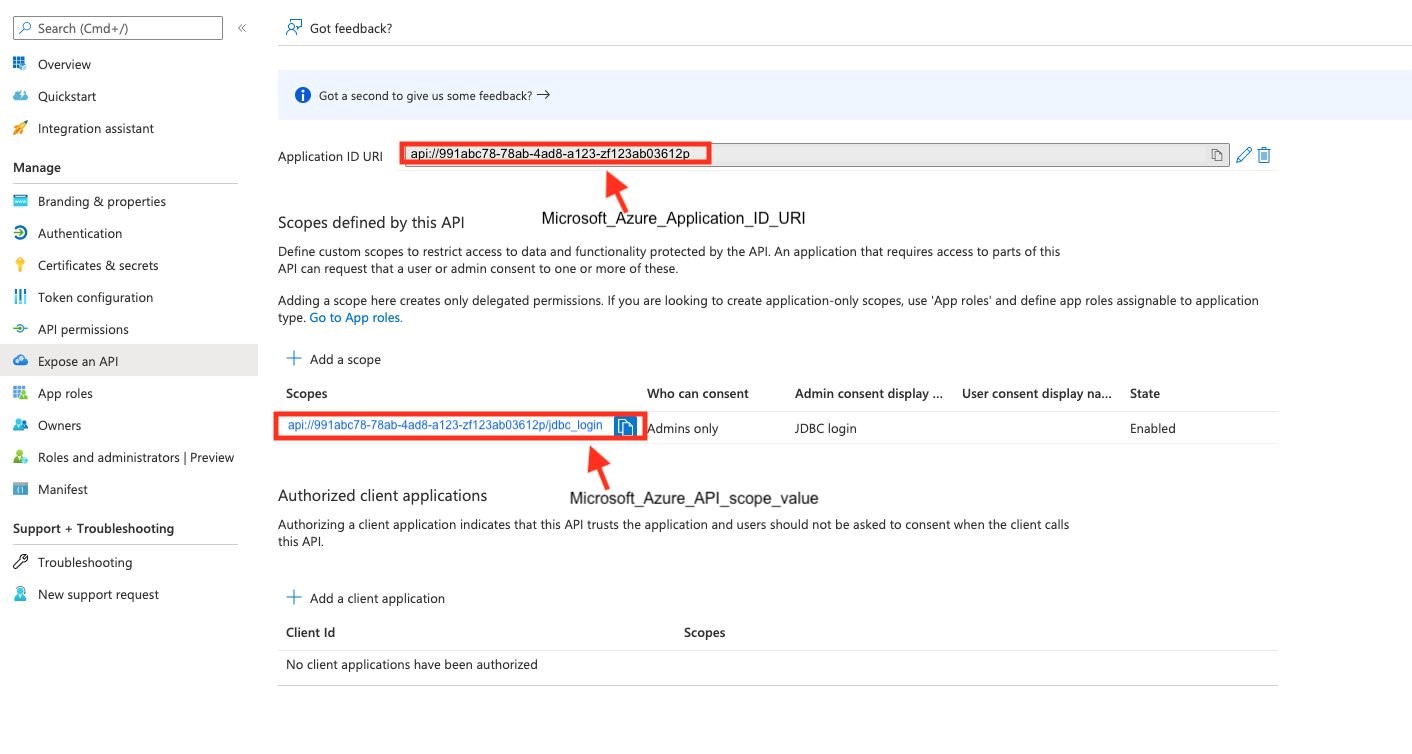
  7. After the scope is added, note down the application ID URI (for example, api://991abc78-78ab-4ad8-a123-zf123ab03612p) and API scope (api://991abc78-78ab-4ad8-a123-zf123ab03612p/jdbc_login) in order to register the IdP in Amazon Redshift later.

The application ID URI is known as <Microsoft_Azure_Application_ID_URI> in the following section.

The API scope is known as <Microsoft_Azure_API_scope_value> when setting up the SQL client such as DBeaver and SQL Workbench/J.

Step 2. Create Redshift Client Application

  1. Navigate to the Azure Active Directory application.
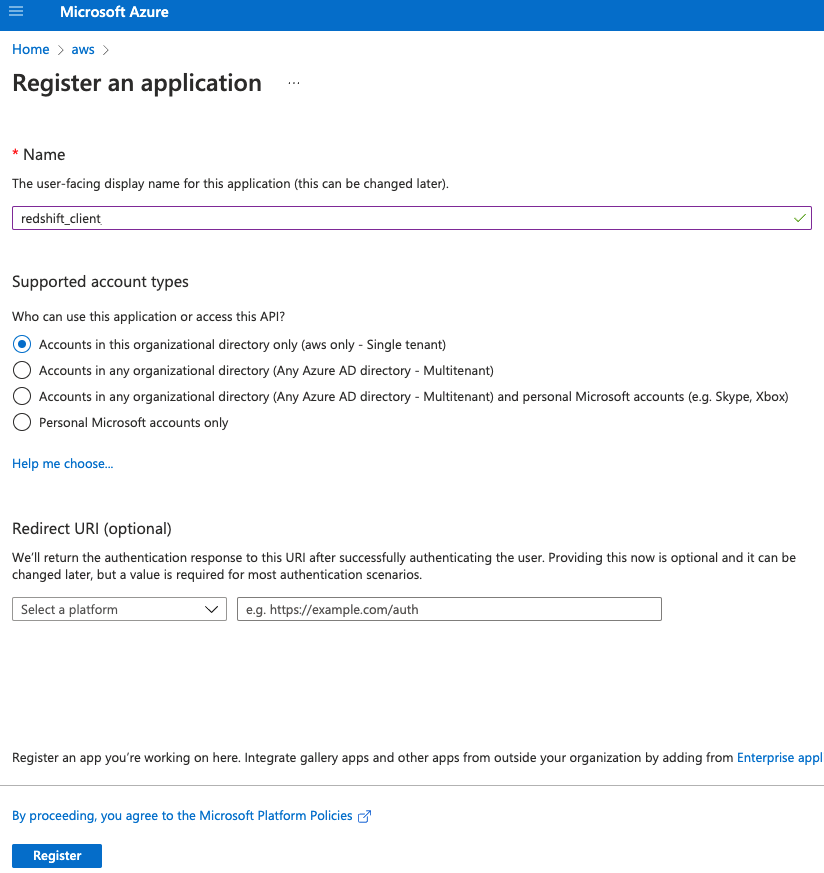
  2. Under Manage in the navigation pane, choose App registrations and then choose New registration.
  3. For Name, enter a name (for example, redshift_client). For this post, we are keeping the default settings for the rest of the fields.
  4. Choose Register.
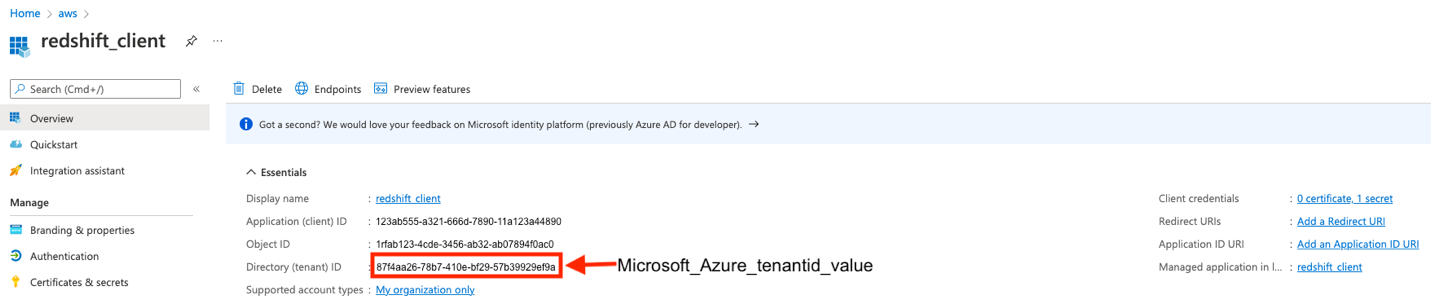
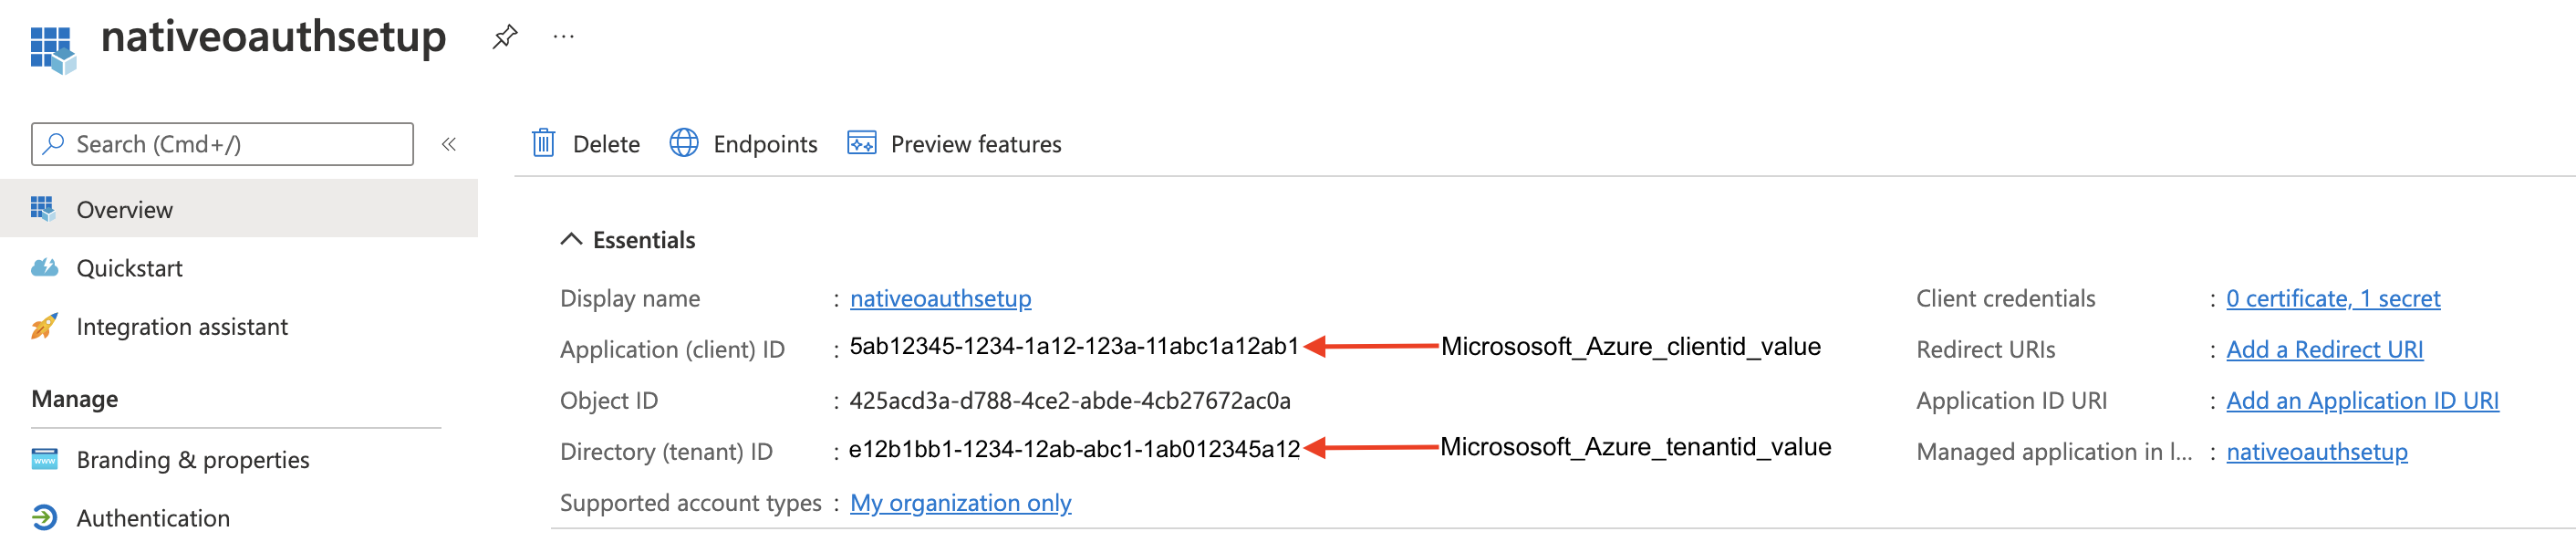
  5. On the newly created application Overview page, locate the client ID and tenant ID and note down these IDs in order to register the IdP in Amazon Redshift later.
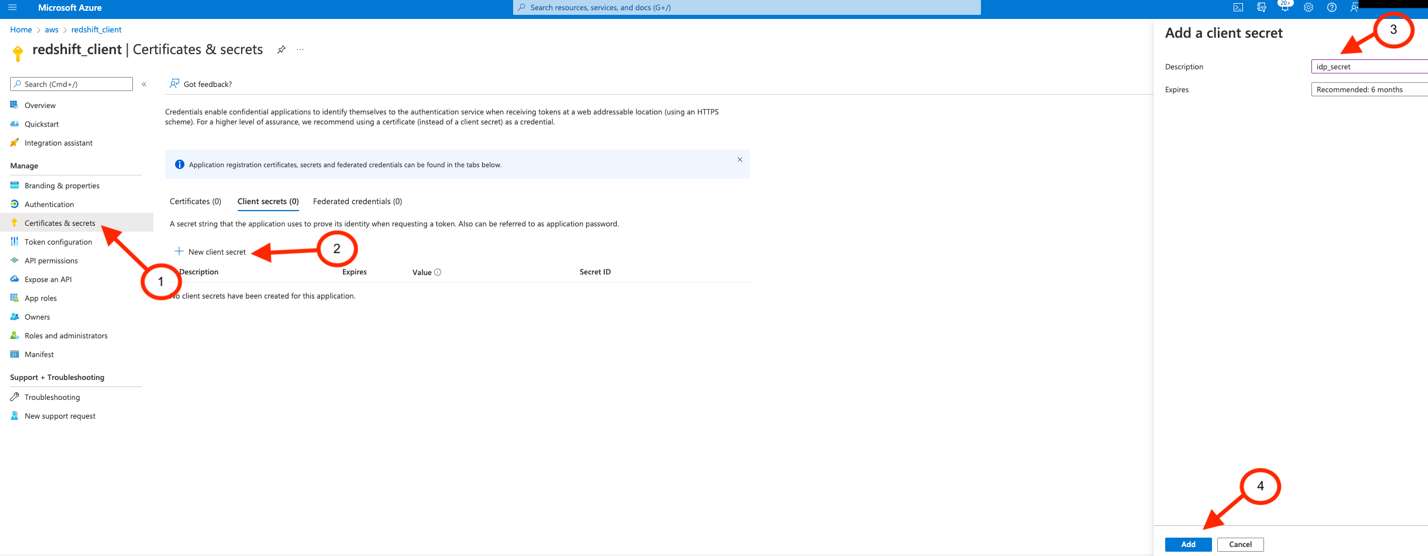
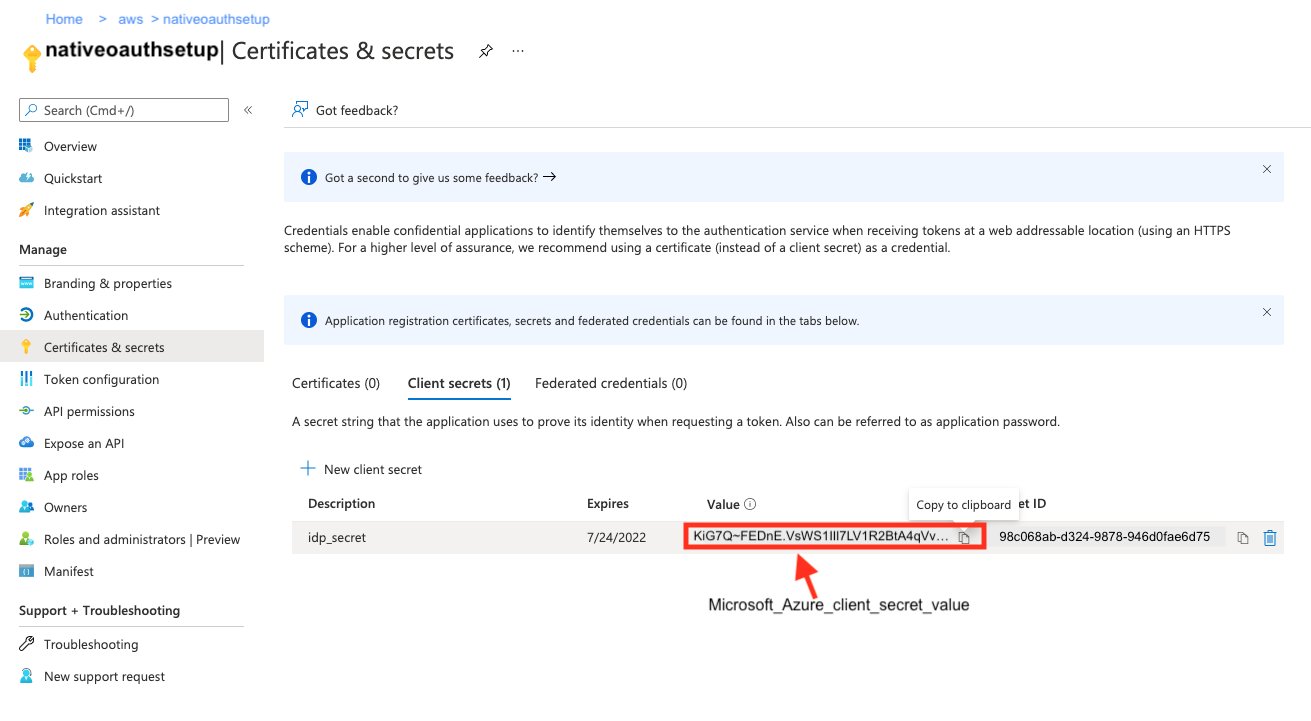
  6. In the navigation pane, choose Certificates & secrets.
  7. Choose New client secret.
  8. Enter a Description, select an expiration for the secret or specify a custom lifetime. We are keeping Microsoft recommended default expiration value of 6 months. Choose Add.
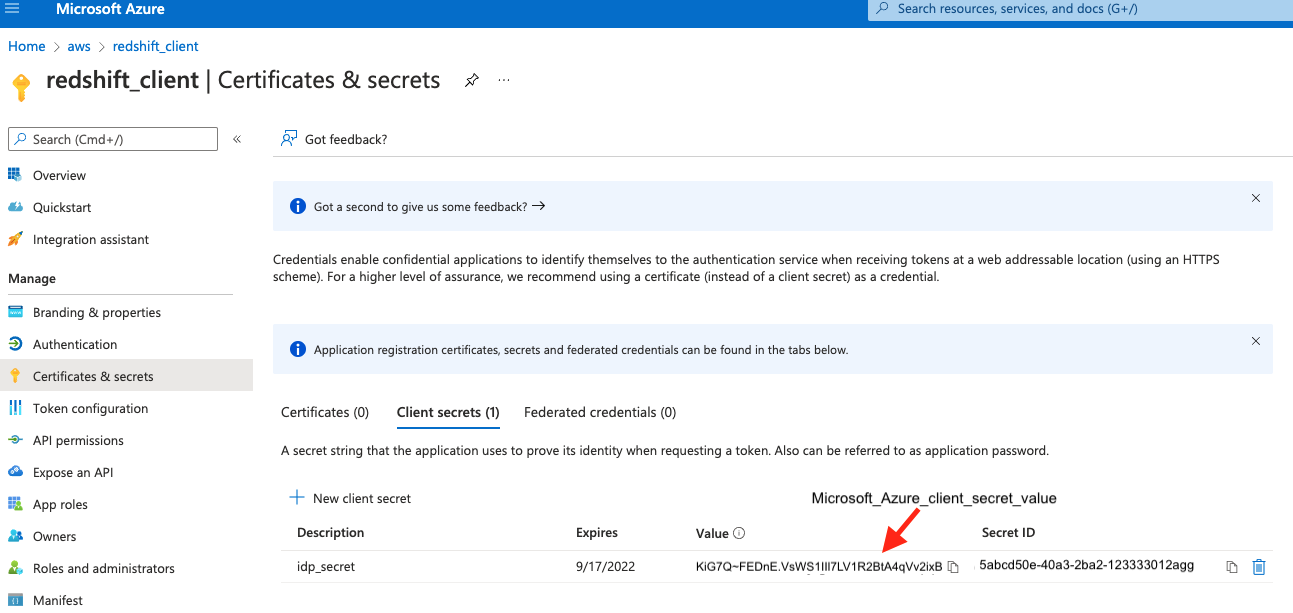
  9. Copy the secret value.

It would only be present one time and after that you cannot read it.

  1. In the navigation pane, choose API permissions.
  2. Choose Add a permission and choose Microsoft Graph.
  3. Choose Application permissions.
  4. Search the directory and select the Directory.Read.All permission.
  5. Choose Add permissions.
  6. After the permission is created, choose Grant admin consent.
  7. In the pop-up box, choose Yes to grant the admin consent.

The status for the permission shows as Granted for with a green check mark.

Step 3. Create Azure AD Group

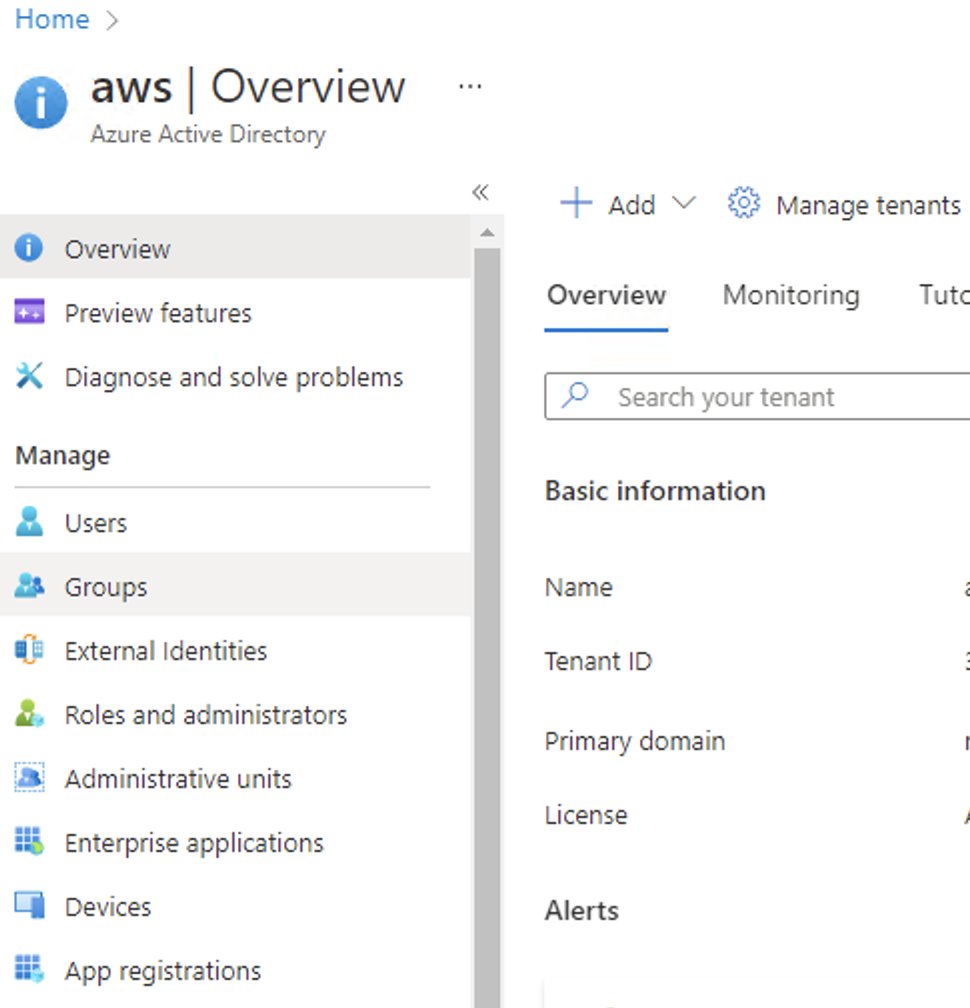
  1. On the Azure AD home page, under Manage, choose Groups.
  2. Choose New group.
  3. In the New Group section, provide the required information.
  4. Choose No members selected and then search for the members.
  5. Select the members and choose Select. For this example, you can search your username and click select.

You can see the number of members in the Members section.

  1. Choose Create.

Collect Azure AD information

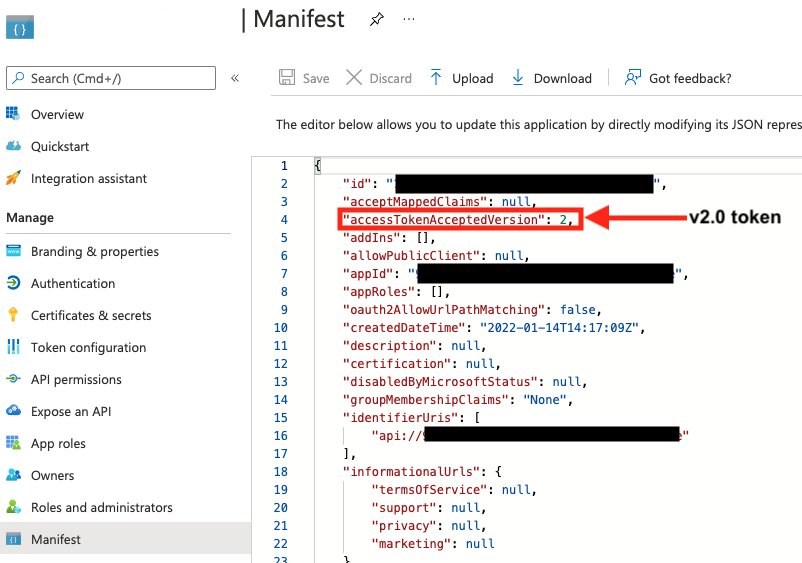
Before we collect the Azure AD information, we need to identify the access token version from the application which you have created earlier on the Azure portal under Step 1. Create OAuth Application. In the navigation pane, under Manage, choose Manifest section, then view the accessTokenAcceptedVersion parameter: null and 1 indicate v1.0 tokens, and 2 indicates v2.0 tokens.

To configure your IdP in Amazon Redshift, collect the following parameters from Azure AD. If you don’t have these parameters, contact your Azure admin.

  1. issuer – This is known as <Microsoft_Azure_issuer_value> in the following sections. If you’re using the v1.0 token, use https://sts.windows.net/<Microsoft_Azure_tenantid_value>/. If you’re using the v2.0 token, use https://login.microsoftonline.com/<Microsoft_Azure_tenantid_value>/v2.0. To find your Azure tenant ID, complete the following steps:
    • Sign in to the Azure portal with your Microsoft account.
    • Under Manage, choose App registrations.
    • Choose any application which you have created in previous sections.
    • Click on the Overview (left panel) page and it’s listed in the Essentials section as Directory (tenant) ID.

  2. client_id – This is known as <Microsoft_Azure_clientid_value> in the following sections. An example of a client ID is 123ab555-a321-666d-7890-11a123a44890). To get your client ID value, locate the application you created earlier on the Azure portal under Step 2. Create Redshift Client Application. Click on the Overview (left panel) page and it’s listed in the Essentials section.
  3. client_secret – This is known as <Microsoft_Azure_client_secret_value> in the following sections. An example of a client secret value is KiG7Q~FEDnE.VsWS1IIl7LV1R2BtA4qVv2ixB). To create your client secret value, refer to the section under Step 2. Create Redshift Client Application.
  4. audience – This is known as <Microsoft_Azure_token_audience_value> in the following sections. If you’re using a v1.0 token, the audience value is the application ID URI (for example, api://991abc78-78ab-4ad8-a123-zf123ab03612p). If you’re using a v2.0 token, the audience value is the client ID value (for example, 991abc78-78ab-4ad8-a123-zf123ab03612p). To get these values, please refer to the application which you have created in Step 1: Create OAuth Application. Click on the Overview (left panel) page and it’s listed in the Essentials section.

Set up the IdP on Amazon Redshift

To set up the IdP on Amazon Redshift, complete the following steps:

  1. Log in to Amazon Redshift with a superuser user name and password using query editor v2 or any SQL client.
  2. Run the following SQL:
    CREATE IDENTITY PROVIDER <idp_name> TYPE azure 
    NAMESPACE '<namespace_name>' 
    PARAMETERS '{ 
    "issuer":"<Microsoft_Azure_issuer_value>", 
    "audience":["<Microsoft_Azure_token_audience_value>"],
    "client_id":"<Microsoft_Azure_clientid_value>", 
    "client_secret":"<Microsoft_Azure_client_secret_value>"
    }';

For example, the following code uses a v1.0 access token:

CREATE IDENTITY PROVIDER test_idp TYPE 
azure NAMESPACE 'oauth_aad' 
PARAMETERS '{
"issuer":"https://sts.windows.net/87f4aa26-78b7-410e-bf29-57b39929ef9a/", 
"audience":["api://991abc78-78ab-4ad8-a123-zf123ab03612p"],
"client_id":"123ab555-a321-666d-7890-11a123a44890", 
"client_secret":"KiG7Q~FEDnE.VsWS1IIl7LV1R2BtA4qVv2ixB"
}';

The following code uses a v2.0 access token:

CREATE IDENTITY PROVIDER test_idp TYPE 
azure NAMESPACE 'oauth_aad' 
PARAMETERS '{
"issuer":
"https://login.microsoftonline.com/87f4aa26-78b7-410e-bf29-57b39929ef9a/v2.0",
"audience":["991abc78-78ab-4ad8-a123-zf123ab03612p"], 
"client_id":"123ab555-a321-666d-7890-11a123a44890", 
"client_secret":"KiG7Q~FEDnE.VsWS1IIl7LV1R2BtA4qVv2ixB" 
}';
  1. To alter the IdP, use the following command (this new set of parameter values completely replaces the current values):
    ALTER IDENTITY PROVIDER <idp_name> PARAMETERS 
    '{
    "issuer":"<Microsoft_Azure_issuer_value>/",
    "audience":["<Microsoft_Azure_token_audience_value>"], 
    "client_id":"<Microsoft_Azure_clientid_value>", 
    "client_secret":"<Microsoft_Azure_client_secret_value>"
    }';

  2. To view a single registered IdP in the cluster, use the following code:
    DESC IDENTITY PROVIDER <idp_name>;

  3. To view all registered IdPs in the cluster, use the following code:
    select * from svv_identity_providers;

  4. To drop the IdP, use the following command:
    DROP IDENTITY PROVIDER <idp_name> [CASCADE];

Set up Amazon Redshift permissions to external identities

The users, roles, and role assignments are automatically created in your Amazon Redshift cluster during the first login using your native IdP unless they were manually created earlier.

Create and assign permission to Amazon Redshift roles

In this step, we create a role in the Amazon Redshift cluster based on the groups that you created on the Azure AD portal. This helps us avoid creating multiple user names manually on the Amazon Redshift side and assign permissions for multiple users individually.

The role name in the Amazon Redshift cluster looks like <namespace>:<azure_ad_group_name>, where the namespace is the one we provided in the IdP creation command and the group name is the one we specified when we were setting up the Azure application. In our example, it’s oauth_aad:rsgroup.

Run the following command in the Amazon Redshift cluster to create a role:

create role "<namespace_name>:<Azure AD groupname>";

For example:

create role "oauth_aad:rsgroup";

To grant permission to the Amazon Redshift role, enter the following command:

GRANT { { SELECT | INSERT | UPDATE | DELETE | DROP | REFERENCES } [,...]
 | ALL [ PRIVILEGES ] }
ON { [ TABLE ] table_name [, ...] | ALL TABLES IN SCHEMA schema_name [, ...] }
TO role "<namespace_name>:<Azure AD groupname>";

Then grant relevant permission to the role as per your requirement. For example:

grant select on all tables in schema public to role "oauth_aad:rsgroup";

Create and assign permission to an Amazon Redshift user

This step is only required if you want to grant permission to an Amazon Redshift user instead of roles. We create an Amazon Redshift user that maps to a Azure AD user and then grant permission to it. If you don’t want to explicitly assign permission to an Amazon Redshift user, you can skip this step.

To create the user, use the following syntax:

CREATE USER "<namespace_name>:<Azure AD username>" PASSWORD DISABLE;

For example:

CREATE USER "oauth_aad:[email protected]" PASSWORD DISABLE;

We use the following syntax to grant permission to the Amazon Redshift user:

GRANT { { SELECT | INSERT | UPDATE | DELETE | DROP | REFERENCES } [,...]
 | ALL [ PRIVILEGES ] }
ON { [ TABLE ] table_name [, ...] | ALL TABLES IN SCHEMA schema_name [, ...] }
TO "<namespace_name>:<Azure AD username>";

For example:

grant select on all tables in schema public to "oauth_aad:[email protected]";

Configure the SQL client

In this section, we provide instructions to set up a SQL client using either DBeaver or SQL Workbench/J.

Set up DBeaver

To set up DBeaver, complete the following steps:

  1. Go to Database and choose Driver Manager.
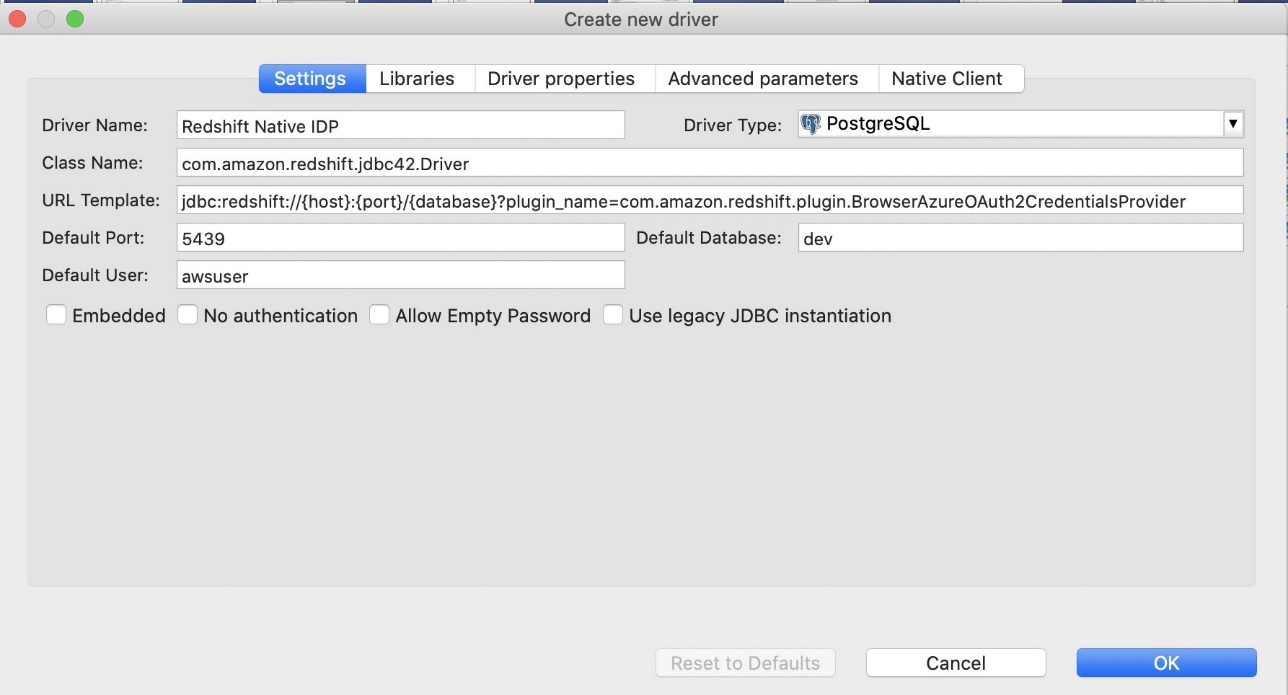
  2. Search for Redshift, then choose it and choose Copy.
  3. On the Settings tab, for Driver name, enter a name, such as Redshift Native IDP.
  4. Update the URL template to jdbc:redshift://{host}:{port}/{database}?plugin_name=com.amazon.redshift.plugin.BrowserAzureOAuth2CredentialsProvider
    Note: In this URL template, do not replace the template parameters with the actual values. Please keep the value as shown in screenshot below.
  5. On the Libraries tab, choose Add files. Keep only one set of the latest driver version (2.1.0.4 and upwards) and if you see any older versions, delete those files.
  6. Add all the files from the downloaded AWS JDBC driver pack .zip file and choose OK (remember to unzip the .zip file).

Note: Use the Amazon Redshift driver 2.1.0.4 onwards, because all previous Amazon Redshift driver versions don’t support the Amazon Redshift native IdP feature.

  1. Close the Driver Manager.
  2. Go to Database and choose New Database Connection.
  3. Search for Redshift Native IDP, then choose it and choose Next.
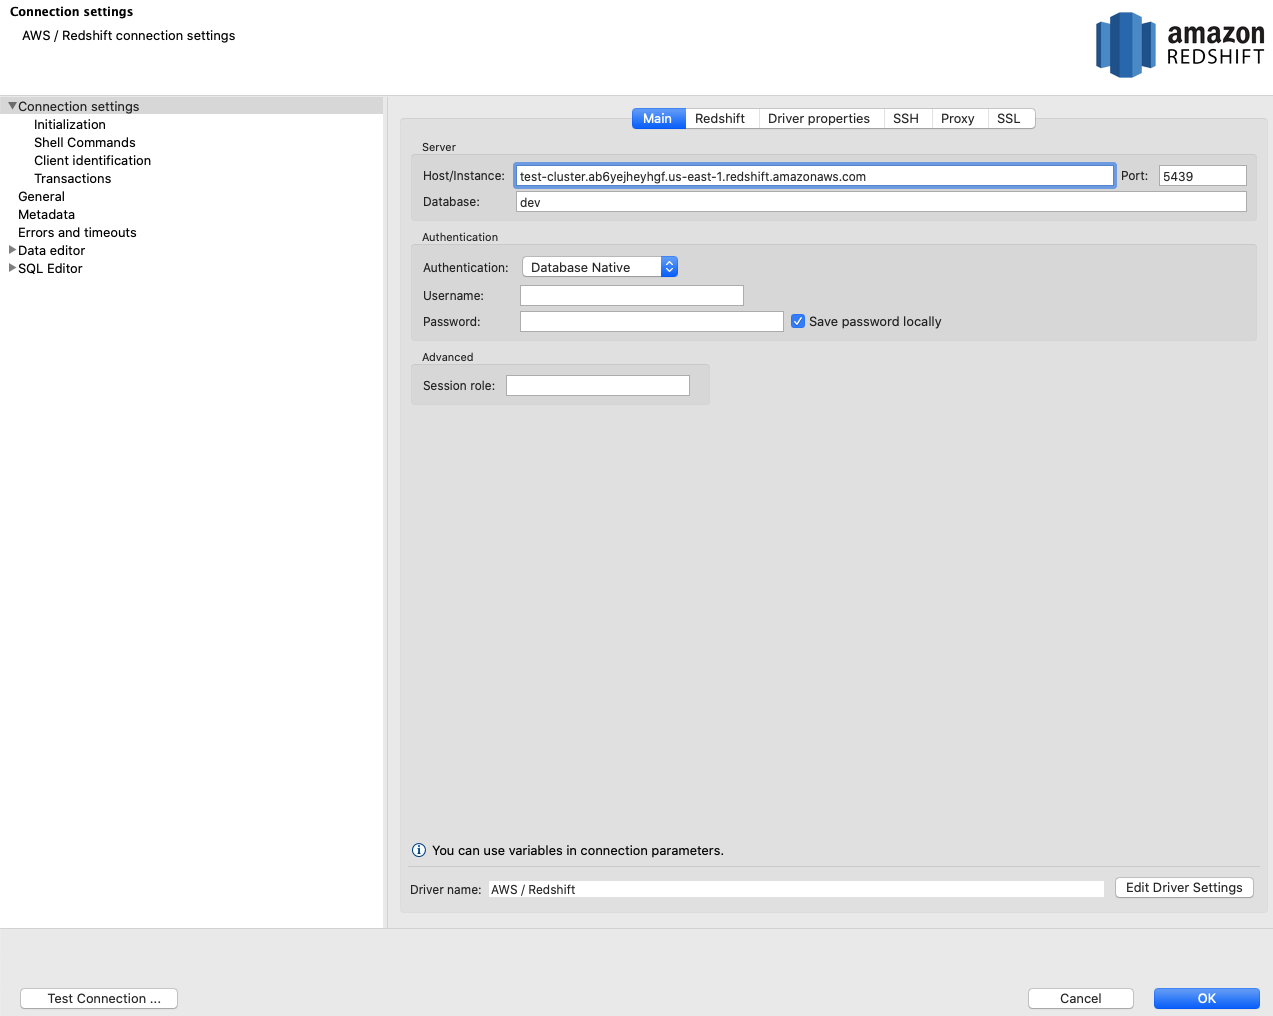
  4. For Host/Instance, enter your Amazon Redshift endpoint. For e.g. test-cluster.ab6yejheyhgf.us-east-1.redshift.amazonaws.com.
  5. For Database, enter the database name (for this post, we use dev).
  6. For Port, enter 5439.
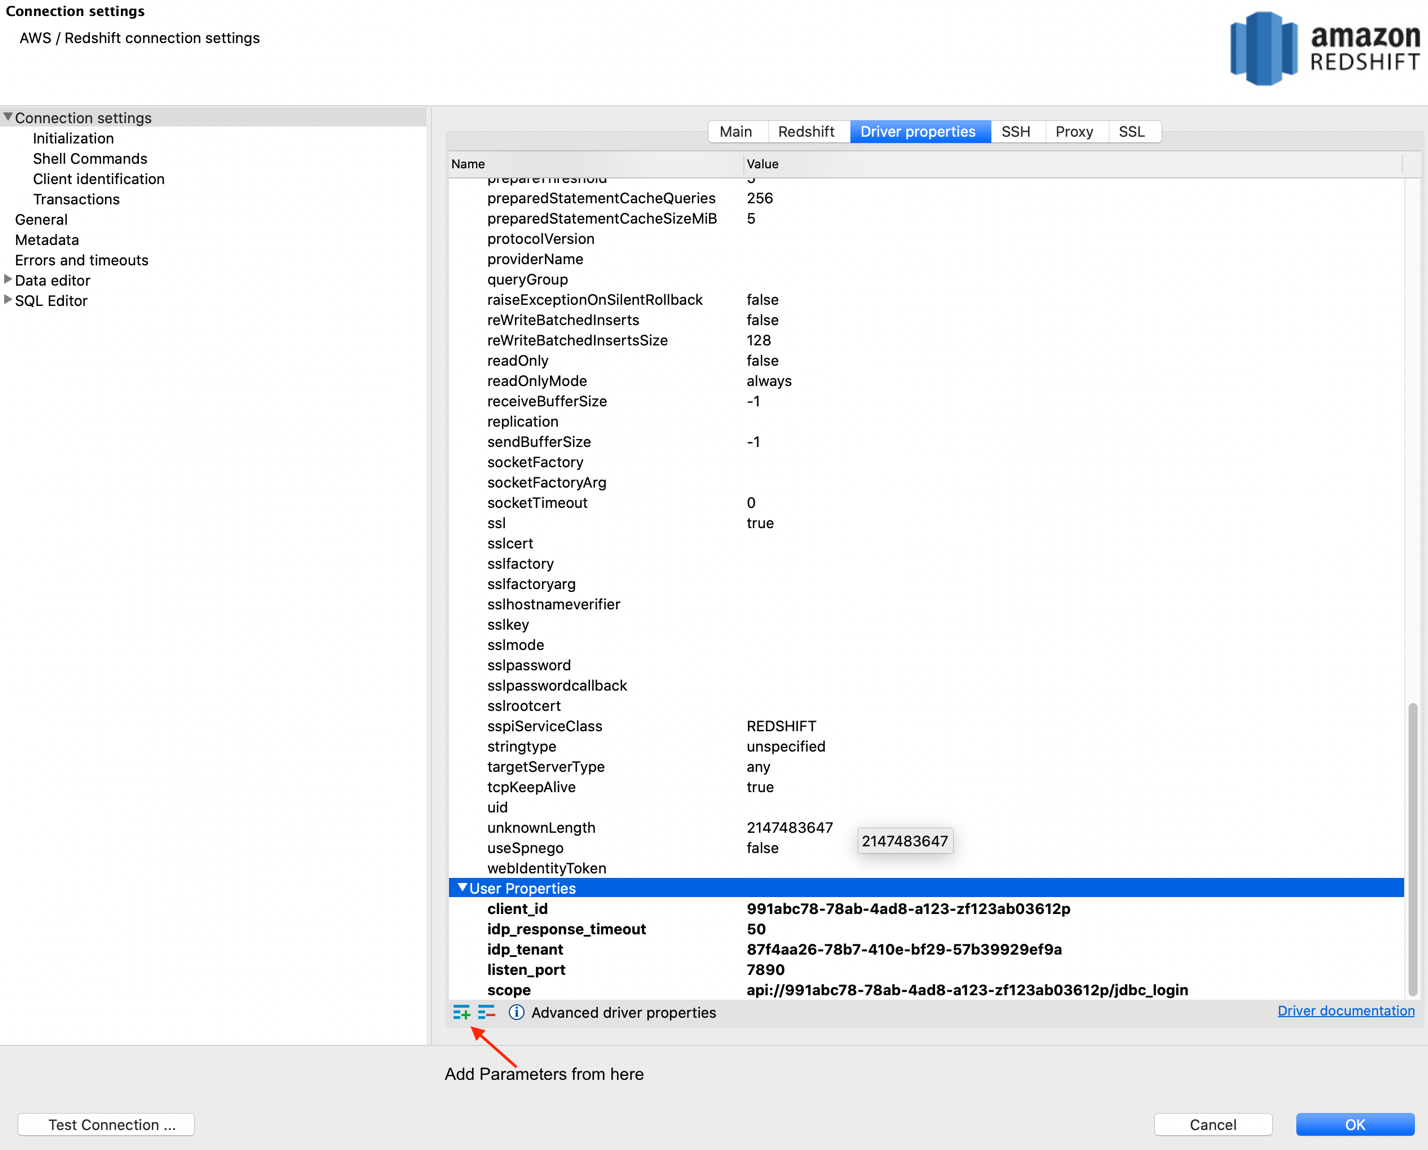
  7. Please get the below parameter values (scope, client_id and idp_tenant) from the application which you have created in Step 1: Create OAuth Application. On the Driver properties tab, add the following properties:
    1. listen_port – 7890
    2. idp_response_timeout – 50
    3. scope – Enter the value for <Microsoft_Azure_API_scope_value>.
      • If you’re using a v1.0 token, then use the scope value (for example, api://991abc78-78ab-4ad8-a123-zf123ab03612p/jdbc_login).
      • If you’re using a v2.0 token, the scope value is the client ID value (for example, 991abc78-78ab-4ad8-a123-zf123ab03612p).
    4. client_id – Enter the value for <Microsoft_Azure_clientid_value>. For example, 991abc78-78ab-4ad8-a123-zf123ab03612p.
    5. idp_tenant – Enter the value for <Microsoft_Azure_tenantid_value>. For example, 87f4aa26-78b7-410e-bf29-57b39929ef9a.
  8. You can verify the connection by choosing Test Connection.

You’re redirected to the browser to sign in with your Azure AD credentials. In case, you get SSL related error, then go to SSL tab and select Use SSL

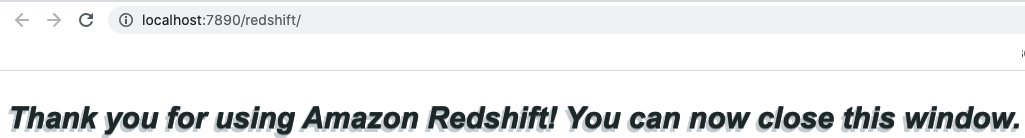
  1. Log in to be redirected to a page showing the connection as successful.
  2. Choose Ok.

Congratulations! You have completed the Amazon Redshift native IdP setup with DBeaver.

Set up SQL Workbench/J

To set up SQL Workbench/J, complete the following steps:

  1. Create a new connection in SQL Workbench/J and choose Amazon Redshift as the driver.
  2. Choose Manage drivers and add all the files from the downloaded AWS JDBC driver pack .zip file (remember to unzip the .zip file).

Use the Amazon Redshift driver 2.1.0.4 onwards, because all previous Amazon Redshift driver versions don’t support the Amazon Redshift native IdP feature.

  1. For URL, enter jdbc:redshift://<cluster endpoint>:<port>:<databasename>. For e.g., jdbc:redshift://test-cluster.ab6yejheyhgf.us-east-1.redshift.amazonaws.com:5439/dev.
  2. Please get the below parameter values (scope, client_id and idp_tenant) from the application which you have created in Step 1: Create OAuth Application. On the Driver properties tab, add the following properties:
    1. plugin_name – com.amazon.redshift.plugin.BrowserAzureOAuth2CredentialsProvider
    2. listen_port – 7890
    3. idp_response_timeout – 50
    4. scope – Enter the value for <Microsoft_Azure_API_scope_value>.
      • If you’re using a v1.0 token, then use the scope value (for example, api://991abc78-78ab-4ad8-a123-zf123ab03612p/jdbc_login).
      • If you’re using a v2.0 token, the scope value is the client ID value (for example, 991abc78-78ab-4ad8-a123-zf123ab03612p).
    5. client_id – Enter the value for <Microsoft_Azure_clientid_value>. For example, 991abc78-78ab-4ad8-a123-zf123ab03612p.
    6. idp_tenant – Enter the value for <Microsoft_Azure_tenantid_value>. For example, 87f4aa26-78b7-410e-bf29-57b39929ef9a.
  3. Choose OK.
  4. Choose Test from SQL Workbench/J.

You’re redirected to the browser to sign in with your Azure AD credentials.

  1. Log in to be redirected to a page showing the connection as successful.
  2. Choose Finish.

    sqlworkbenchj-test-successful
  3. With this connection profile, run the following query to test Amazon Redshift native IdP authentication.
    sqlworkbenchj-current-user

Congratulations! You have completed the Amazon Redshift native IdP setup with SQL Workbench/J.

Best Practices with Redshift native IdP:

  • Pre-create the Amazon Redshift roles based upon the groups which you have created on the Azure AD portal.
  • Assign permissions to Redshift roles instead of assigning to each individual external user. This will provide smoother end user experience as user will have all the required permission when they login using native IdP.

Troubleshooting

If your connection didn’t work, consider the following:

  • Enable logging in the driver. For instructions, see Configure logging.
  • Make sure to use the latest Amazon Redshift JDBC driver version 2.1.0.4 onwards, which supports Amazon Redshift native IdP authentication.
  • If you’re getting errors while setting up the application on Azure AD, make sure you have admin access.
  • If you can authenticate via the SQL client but get a permission issue or can’t see objects, grant the relevant permission to the role, as detailed earlier in this post.
  • If you get the error “claim value does not match expected value,” make sure you provided the correct parameters during Amazon Redshift IdP registration.
  • Check stl_error or stl_connection_log views on the Amazon Redshift cluster for authentication failures.

Conclusion

In this post, we provided step-by-step instructions to integrate Amazon Redshift with Azure AD and SQL clients (SQL Workbench/J and DBeaver) using Amazon Redshift native IdP authentication. We also showed how Azure group membership is mapped automatically with Amazon Redshift roles and how to set up Amazon Redshift permissions.

For more information about Amazon Redshift native IdP federation, see:


About the Authors

Maneesh Sharma is a Senior Database Engineer at AWS with more than a decade of experience designing and implementing large-scale data warehouse and analytics solutions. He collaborates with various Amazon Redshift Partners and customers to drive better integration.

Debu-PandaDebu Panda is a Senior Manager, Product Management at AWS. He is an industry leader in analytics, application platform, and database technologies, and has more than 25 years of experience in the IT world.

Ilesh Garish is a Software Development Engineer at AWS. His role is to develop connectors for Amazon Redshift. Prior to AWS, he built database drivers for the Oracle RDBMS, TigerLogic XDMS, and OpenAccess SDK. He also worked in the database internal technologies at San Francisco Bay Area startups.

Dengfeng(Davis) Li is a Software Development Engineer at AWS. His passion is creating ease-of-use, secure and scalable applications. In the past few years, he worked on Redshift security, data sharing and catalog optimization.

Integrate Amazon Redshift native IdP federation with Microsoft Azure AD and Power BI

Post Syndicated from Maneesh Sharma original https://aws.amazon.com/blogs/big-data/integrate-amazon-redshift-native-idp-federation-with-microsoft-azure-ad-and-power-bi/

Amazon Redshift accelerates your time to insights with fast, easy, and secure cloud data warehousing at scale. Tens of thousands of customers rely on Amazon Redshift to analyze exabytes of data and run complex analytical queries.

As enterprise customers look to build their data warehouse on Amazon Redshift, they have many integration needs with the business intelligence (BI) tools they’re using. For customers who want to integrate Amazon Redshift with their existing identity provider (IdP) such as Microsoft Azure Active Directory (Azure AD) using BI tools and services such as Power BI Desktop and Power BI service, we have introduced a native IdP for Amazon Redshift to help you implement authentication and authorization for these tools in a seamless way.

Amazon Redshift native IdP simplifies the administration process of managing identities and permission. This feature provides native integration with Microsoft Azure AD, which you can use for authentication and authorization with tools like Power BI. It uses your existing IdP to simplify authentication and managing permissions. It does this by making it possible to share identity metadata to Amazon Redshift from your IdP. In this approach, an external IdP (such as Azure AD) issues an access token, which is passed to Amazon Redshift via a client, and then Amazon Redshift performs the token validation and claim extraction natively.

This post shows a step-by-step implementation of the Amazon Redshift native IdP setup with Azure AD, which demonstrates how to manage users and groups with an organizational directory, and how to federate into Amazon Redshift. You don’t need to create AWS Identity and Access Management (IAM) roles, policies, separate database users, or groups in Amazon Redshift with this setup.

Solution overview

Using an Amazon Redshift native IdP has the following benefits:

  • You can manage users and groups from a centralized IdP
  • Enables your users to be automatically signed in to Amazon Redshift with their Azure AD accounts
  • You can automatically create Amazon Redshift roles with a namespace that represents external groups (such as Azure AD groups)
  • External user group membership is natively mirrored with Amazon Redshift roles and users

The general configuration steps of the Amazon Redshift native IdP approach are as follows:

  1. Register an application in Azure AD and set up groups.
  2. Collect Azure AD information for the Amazon Redshift IdP.
  3. Set up the IdP on Amazon Redshift.
  4. Set up Amazon Redshift permissions to external identities.
  5. Configure the client connection.

The following diagram illustrates the resulting solution.

To get authorized, the Power BI client sends an authentication request to the Azure enterprise application using Azure AD credentials. After verification, Azure sends a JSON web token (OAuth token) to the Power BI application. The Power BI application forwards the connection string with the OAuth token to Amazon Redshift. Amazon Redshift parses and validates the token, and requests group information from Azure AD. Upon reception, Amazon Redshift automatically creates the user and roles, and does the respective mapping.

Prerequisites

You need the following prerequisites to set up this solution:

  • A Microsoft Azure account that has an active subscription. You need to an admin role to set up the application on Azure AD.
  • Power BI Desktop version 2.102.683.0 64-bit and above downloaded and installed. In this example, we have use a Windows environment.
  • The latest version of the Microsoft Enterprise/Standard Gateway installed.
  • An AWS account with an Amazon Redshift cluster. In this post, we connect Power BI Desktop and service with a publicly accessible Amazon Redshift cluster.

Register an application in Azure AD and set up groups

To set up the Azure application and group permission, complete the following steps:

  1. Sign in to the Azure portal with your Microsoft account.
  2. Navigate to the Azure Active Directory application.
  3. Under Manage, choose App registrations and New registration.
  4. For Name, enter an application name (for example, nativeoauthsetup).
  5. Keep the default settings for the rest of the fields.
  6. Choose Register to complete the initial application registration.
  7. On the newly created application Overview page, locate the client ID and tenant ID and note down these IDs in order to register the IdP in Amazon Redshift later.
  8. Under Manage in the navigation pane, choose API permissions.
  9. Choose Add a permission.
  10. Choose Microsoft Graph and then choose Application permissions.
  11. Search for directory and select the Directory.Read.All permission.
  12. Choose Add permissions.
  13. Choose Grant admin consent.
  14. In the popup box, choose Yes to grant the admin consent.

The status of the permission shows Granted for with a green check mark.

  1. Under Manage in the navigation pane, choose Certificates & secrets.
  2. Choose Client secrets and choose New client secret.
  3. Enter a Description, select an expiration for the secret or specify a custom lifetime. We are keeping Microsoft recommended default expiration value of 6 months. Choose Add.
  4. Copy the secret value.

It would only be present one time and after that you cannot read it.

  1. On the Azure AD home page, under Manage in the navigation pane, choose Groups.
  2. Choose New group.
  3. In the New Group section, provide the required information.
  4. Choose No members selected and then search for the members.
  5. Select your members and choose Select. For this example, you can search your username and click select.

You can see the number of members in the Members section.

  1. Choose Create.

Collect Azure AD Information for Amazon Redshift IdP

Before we collect the Azure AD information, we need to identify the access token version from the application which you have created earlier. In the navigation pane, under Manage, choose Manifest section, then view the accessTokenAcceptedVersion parameter: null and 1 indicate v1.0 tokens, and 2 indicates v2.0 tokens.

To configure your IdP in Amazon Redshift, collect the following parameters from Azure AD. If don’t have these parameters, contact your Azure admin.

  • issuer – This is known as <Microsoft_Azure_issuer_value>. If you’re using the v1.0 token, use https://sts.windows.net/<Microsoft_Azure_tenantid_value>/. Currently, Power BI only uses v1.0 token. If you’re using the v2.0 token, use https://login.microsoftonline.com/<Microsoft_Azure_tenantid_value>/v2.0. To find your Microsoft Azure tenant ID, complete the following steps:
    • Sign in to the Azure portal with your Microsoft account.
    • Under Manage, choose App registrations.
    • Choose the Amazon Redshift application you created earlier.
    • Click on the Overview (left panel) page and under Essentials, note down the values.
  • client_id – This is known as <Microsoft_Azure_clientid_value> in the following sections. An example of a client ID is 5ab12345-1234-1a12-123a-11abc1a12ab1). To get your client ID value, locate the Amazon Redshift application you created earlier on the Azure portal; it’s listed in the Essentials section.
  • client_secret – This is known as <Microsoft_Azure_client_secret_value> in the following sections. An example of a client secret value is KiG7Q~FEDnE.VsWS1IIl7LV1R2BtA4qVv2ixB). To create your client secret value, refer to the steps in the previous section.
  • audience – This is known as <Microsoft_Azure_token_audience_value> in the following sections. With Power BI Desktop, you need to set the audience value as https://analysis.windows.net/powerbi/connector/AmazonRedshift.

Set up the IdP on Amazon Redshift

To set up the IdP on Amazon Redshift, complete the following steps:

  1. Log in to Amazon Redshift with a superuser user name and password using query editor v2 or any SQL client.
  2. Run the following SQL:
    CREATE IDENTITY PROVIDER <idp_name> TYPE azure 
    NAMESPACE '<namespace_name>' 
    PARAMETERS '{ 
    "issuer":"<Microsoft_Azure_issuer_value>", 
    "audience":["<Microsoft_Azure_token_audience_value>"],
    "client_id":"<Microsoft_Azure_clientid_value>", 
    "client_secret":"<Microsoft_Azure_client_secret_value>"
    }';

In our example, we use the v1.0 token issuer because as of this writing, Power BI only uses the v1.0 token:

CREATE IDENTITY PROVIDER oauth_standard TYPE azure
NAMESPACE 'aad'
PARAMETERS '{
"issuer":"https://sts.windows.net/e12b1bb1-1234-12ab-abc1-1ab012345a12/",
"audience":["https://analysis.windows.net/powerbi/connector/AmazonRedshift"],
"client_id":"5ab12345-1234-1a12-123a-11abc1a12ab1",
"client_secret":"KiG7Q~FEDnE.VsWS1IIl7LV1R2BtA4qVv2ixB"
}'
  1. To alter the IdP, use the following command (this new set of parameter values completely replaces the current values):
    ALTER IDENTITY PROVIDER <idp_name> PARAMETERS 
    '{
    "issuer":"<Microsoft_Azure_issuer_value>",
    "audience":["<Microsoft_Azure_token_audience_value>"], 
    "client_id":"<Microsoft_Azure_clientid_value>", 
    "client_secret":"<Microsoft_Azure_client_secret_value>"
    }';

  2. To view a single registered IdP in the cluster, use the following code:
    DESC IDENTITY PROVIDER <idp_name>;

  3. To view all registered IdPs in the cluster, use the following code:
    select * from svv_identity_providers;

  4. To drop the IdP, use the following command:
    DROP IDENTITY PROVIDER <idp_name> [CASCADE];

Set up Amazon Redshift permissions to external identities

The users, roles, and role assignments are automatically created in your Amazon Redshift cluster during the first login using your native IdP unless they were manually created earlier.

Create and assign permission to Amazon Redshift roles

In this step, we create a role in the Amazon Redshift cluster based on the groups that you created on the Azure AD portal.

The role name in the Amazon Redshift cluster looks like <namespace>:<azure_ad_group_name>, where the namespace is the one we provided in the IdP creation command and the group name is the one we specified when we were setting up the Azure application. In our example, it’s aad:rsgroup.

Run the following command in the Amazon Redshift cluster:

create role "<namespace_name>:<Azure AD groupname>";

For example:

create role "aad:rsgroup";

To grant permission to the Amazon Redshift role, enter the following command:

GRANT { { SELECT | INSERT | UPDATE | DELETE | DROP | REFERENCES } [,...]
 | ALL [ PRIVILEGES ] }
ON { [ TABLE ] table_name [, ...] | ALL TABLES IN SCHEMA schema_name [, ...] }
TO role "<namespace_name>:<Azure AD groupname>";

Then grant relevant permission to the role as per your requirement. For example:

grant select on all tables in schema public to role "aad:rsgroup";

Create and assign permission to an Amazon Redshift user

This step is only required if you want to grant permission to an Amazon Redshift user instead of roles. We create an Amazon Redshift user that maps to a Azure AD user and then grant permission to it. If you don’t want to explicitly assign permission to an Amazon Redshift user, you can skip this step.

To create the user, use the following syntax:

CREATE USER "<namespace_name>:<Azure AD username>" PASSWORD DISABLE;

For example:

CREATE USER "aad:[email protected]" PASSWORD DISABLE;

We use the following syntax to grant permission to the Amazon Redshift user:

GRANT { { SELECT | INSERT | UPDATE | DELETE | DROP | REFERENCES } [,...]
 | ALL [ PRIVILEGES ] }
ON { [ TABLE ] table_name [, ...] | ALL TABLES IN SCHEMA schema_name [, ...] }
TO "<namespace_name>:<Azure AD username>";

For example:

grant select on all tables in schema public to "aad:[email protected]"

Configure your client connection using an Amazon Redshift native IdP

In this section, we provide instructions to set up your client connection for either Power BI Desktop or the Power BI service.

Connect Power BI Desktop

In this example, we use Power BI Desktop to connect with Amazon Redshift using a native IdP. Use Power BI Desktop version: 2.102.683.0 64-bit and above.

  1. In your Power BI Desktop, choose Get data.
  2. Search for the Amazon Redshift connector, then choose it and choose Connect.
  3. For Server, enter your Amazon Redshift cluster’s endpoint. For example, test-cluster.ct4abcufthff.us-east-1.redshift.amazonaws.com.
  4. For Database, enter your database name. In this example, we use dev.
  5. Choose OK.
  6. Choose Microsoft Account.
  7. Choose Sign in.
  8. Enter your Microsoft Account credentials.

When you’re connected, you can see the message You are currently signed in.

  1. Choose Connect.

Congratulations! You are signed in using the Amazon Redshift native IdP with Power BI Desktop. Now you can browse your data.

After that, you can create your own Power BI report on the desktop version and publish it to your Microsoft account. For this example, we created and published a report named RedshiftOAuthReport, which I refer to later in this post.

Connect Power BI service

Now, let’s connect a Power BI gateway with Amazon Redshift using a native IdP. Before proceeding with below setup, please make sure you have downloaded and installed the latest version of the Microsoft Enterprise/Standard Gateway.

  1. Open the Power BI web application and sign in if necessary.

You can see the RedshiftOAuthReport report that we created earlier.

  1. In the navigation pane, under Datasets, choose the menu icon (three dots) next to the report name and then choose Settings.
  2. Enable Gateway connection on the settings page.
  3. Click on the arrow on right side and select Manually add to gateway.

  4. In the Data Source Settings section, enter the appropriate values:
    1. For Data Source Name, enter a name.
    2. For Data Source Type, choose Amazon Redshift.
    3. For Server, enter your Amazon Redshift cluster’s endpoint.
    4. For Database, enter your database name (for this post, we use dev).
    5. For Authentication Method, choose OAuth2.
  5. Choose Edit credentials.
  6. In the pop-up box, choose Sign in.
  7. Enter your Microsoft account credentials and follow the authentication process.
  8. After the authentication, choose Add on the Data Source Settings page.
  9. Make sure that Gateway connection is enabled. If not, enable it.
  10. Select your gateway from the gateway list.
  11. On the Maps to menu, choose your data source.
  12. Choose Apply.

Congratulations! You have completed the Amazon Redshift native IdP setup with Power BI web service.

Best Practices with Redshift native IdP:

  • Pre-create the Amazon Redshift roles based upon the groups which you have created on the Azure AD portal.
  • Assign permissions to Redshift roles instead of assigning to each individual external user. This will provide smoother end user experience as user will have all the required permission when they login using native IdP.

Troubleshooting

If your connection didn’t work, consider the following:

  • Enable logging in the driver. For instructions, see Configure logging.
  • Make sure to use the latest Amazon Redshift JDBC driver version 2.1.0.4 onwards, which supports Amazon Redshift native IdP authentication.
  • If you’re getting errors while setting up the application on Azure AD, make sure you have admin access.
  • If you can authenticate via the SQL client but get a permission issue or can’t see objects, grant the relevant permission to the role, as detailed earlier in this post.
  • If you get the error “claim value does not match expected value,” make sure you provided the correct parameters during Amazon Redshift IdP registration.
  • Check stl_error or stl_connection_log views on the Amazon Redshift cluster for authentication failures.

Summary

In this post, we covered the step-by-step process of integrating Amazon Redshift with Azure AD and Power BI Desktop and web service using Amazon Redshift native IdP federation. The process consisted of registering a Azure application, creating Azure AD groups, setting up the Amazon Redshift IdP, creating and assigning permission to Amazon Redshift roles, and finally configuring client connections.

For more information about Amazon Redshift native IdP federation, see:

If you have questions or suggestions, please leave a comment.


About the Authors

Maneesh Sharma is a Senior Database Engineer at AWS with more than a decade of experience designing and implementing large-scale data warehouse and analytics solutions. He collaborates with various Amazon Redshift Partners and customers to drive better integration.

Ilesh Garish is a Software Development Engineer at AWS. His role is to develop connectors for Amazon Redshift. Prior to AWS, he built database drivers for the Oracle RDBMS, TigerLogic XDMS, and OpenAccess SDK. He also worked in the database internal technologies at San Francisco Bay Area startups.

Debu-PandaDebu Panda is a Senior Manager, Product Management at AWS. He is an industry leader in analytics, application platform, and database technologies, and has more than 25 years of experience in the IT world.

Sergey Konoplev is a Senior Database Engineer on the amazon Redshift Team at AWS. Sergey has been focusing on Automation and improvement of database and data operations for more than a decade.

Simplify management of database privileges in Amazon Redshift using role-based access control

Post Syndicated from Milind Oke original https://aws.amazon.com/blogs/big-data/simplify-management-of-database-privileges-in-amazon-redshift-using-role-based-access-control/

Amazon Redshift is a fully managed, petabyte-scale data warehouse service in the cloud. With Amazon Redshift, you can analyze all your data to derive holistic insights about your business and your customers. One of the challenges with security is that enterprises don’t want to have a concentration of superuser privileges amongst a handful of users. Instead, enterprises want to design their overarching security posture based on the specific duties performed via roles and assign these elevated privilege roles to different users. By assigning different privileges to different roles and assigning these roles to different users, enterprises can have more granular control of elevated user access.

In this post, we explore the role-based access control (RBAC) features of Amazon Redshift and how you can use roles to simplify managing privileges required to your end-users. We also cover new system views and functions introduced alongside RBAC.

Overview of RBAC in Amazon Redshift

As a security best practice, it’s recommended to design security by applying the principle of least privileges. In Amazon Redshift, RBAC applies the same principle to users based on their specific work-related role requirements, regardless of the type of database objects involved. This granting of privileges is performed at a role level, without the need to grant permissions for the individual user or user groups. You have four system-defined roles to get started, and can create additional, more granular roles with privileges to run commands that used to require the superuser privilege. With RBAC, you can limit access to certain commands and assign roles to authorized users. And you can assign object-level as well as system-level privileges to roles across Amazon Redshift native objects.

System-defined roles in Amazon Redshift

Amazon Redshift provides four system-defined roles that come with specific privileges. These can’t be altered or customized, but you can create your own roles as required. The system-defined roles use the sys: prefix, and you can’t use this prefix for the roles you create.

The following table summarizes the roles and their privileges.

Role Name Description of Privileges
sys:operator Can access catalog or system tables, and analyze, vacuum, or cancel queries.
sys:dba Can create schemas, create tables, drop schemas, drop tables, truncate tables, create or replace stored procedures, drop procedures, create or replace functions, create or replace external functions, create views, and drop views. Additionally, this role inherits all the privileges from the sys:operator role.
sys:superuser Has the same privileges as the Amazon Redshift superuser.
sys:secadmin Can create users, alter users, drop users, create roles, drop roles, and grant roles. This role can have access to user tables only when the privilege is explicitly granted to the role.

System privileges

Amazon Redshift also adds support for system privileges that can be granted to a role or a user. A system privilege allows admins to grant a limited set of privileges to a user, such as the ability to create and alter users. These system-defined privileges are immutable and can’t be altered, removed, or added to.

Create custom roles for RBAC in Amazon Redshift

To further granularize the system privileges being granted to users to perform specific tasks, you can create custom roles that authorize users to perform those specific tasks within the Amazon Redshift cluster.

RBAC also supports nesting of roles via role hierarchy, and Amazon Redshift propagates privileges with each role authorization. In the following example, granting role R1 to role R2 and then granting role R2 to role R3 authorizes role R3 with all the privileges from the three roles. Therefore, by granting role R3 to a user, the user has all the privileges from roles R1, R2, and R3.

Amazon Redshift doesn’t allow creation of a cyclic role authorization cycle, so role R3 can’t be granted to role R1, as that would be cyclic role authorization.

You can use the Amazon Redshift commands for privileges to create role, grant role, revoke role, and the admin options for the grant and revoke. Only superusers or regular users who have been granted create role privileges can use those commands.

RBAC example use cases

For this post, we use the industry standard TPC-H dataset to demonstrate our example use cases.

We have three different teams in the organization: Sales, Marketing, and Admin. For this example, we have two schemas, sales and marketing, in the Amazon Redshift database. Each schema has the following tables: nation, orders, part, partsupp, supplier, region, customer, and lineitem.

We have two different database roles, read-only and read/write, for both the Sales team and Marketing team individually. Each role can only perform operations to the objects belonging to the schema to which the role is assigned. For example, a role assigned to the sales schema can only perform operations based on assigned privileges to the sales schema, and can’t perform any operation on the marketing schema.

The read-only role has read-only access to the objects in the respective schema when the privilege is granted to the objects.

The read/write role has read and write (insert, update) access to the objects in the respective schema when the privileges are granted to the objects.

The Sales team has read-only ( role name sales_ro) and read/write ( role name sales_rw) privileges.

The Marketing team has similar roles: read-only ( role name marketing_ro) and read/write ( role name marketing_rw).

The Admin team has one role (db_admin), which has privileges to drop or create database roles, truncate tables, and analyze the entire database. The admin role can perform at the database level across both sales and marketing schemas.

Set up for the example use cases

To set up for the example use cases, create a database admin role and attach it to a database administrator. A superuser must perform all these steps.

All the queries for this post are run in the Amazon Redshift native Query Editor v2, but can be run just the same in any query editor, such as SQLWorkbench/J.

  1. Create the admin role (db_admin):
    create role db_admin;

  2. Create a database user named dbadmin:
    create user dbadmin password 'Test12345';

  3. Assign a system-defined role named sys:dba to the db_admin role:
    grant role sys:dba to role db_admin;

This role has the privileges to create schemas, create tables, drop schemas, drop tables, truncate tables, create or replace stored procedures, drop procedures, create or replace functions, create or replace external functions, create views, drop views, access catalog or system tables, analyze, vacuum, and cancel queries.

  1. Assign a system-defined role named sys:secadmin to the db_admin role:
    grant role sys:secadmin to role db_admin;

This role has the privileges to create users, alter users, drop users, create roles, drop roles, and grant roles.

  1. Assign the user dbadmin to the db_admin role:
    grant role db_admin to dbadmin;

From this point forward, we use the dbadmin user credential for performing any of the following steps when no specific user is mentioned.

  1. Create the sales and marketing database schema:
    create schema sales;
    
    create schema marketing;

  2. Create all the eight tables (nation, orders, part, partsupp, supplier, region, customer, lineitem) in the sales and marketing schemas.

You can use the DDL available on the GitHub repo to create and populate the tables.

After the tables are created and populated, let’s move to the example use cases.

Example 1: Data read-only task

Sales analysts may want to get the list of suppliers with minimal cost. For this, the sales analyst only needs read-only access to the tables in the sales schema.

  1. Let’s create the read-only role (sales_ro) in the sales schema:
    create role sales_ro;

  2. Create a database user named salesanalyst:
    create user salesanalyst password 'Test12345';

  3. Grant the sales schema usage and select access to objects of the sales schema to the read-only role:
    grant usage on schema sales to role sales_ro;
    
    grant select on all tables in schema sales to role sales_ro;

  4. Now assign the user to the read-only sales role:
    grant role sales_ro to salesanalyst;

Now the salesanalyst database user can access the sales schema in the Amazon Redshift database using the salesanalyst credentials.

The salesanalyst user can generate a report of least-expensive suppliers using the following query:

set search_path to sales;
SELECT	TOP 100
	S_ACCTBAL,
	S_NAME,
	N_NAME,
	P_PARTKEY,
	P_MFGR,
	S_ADDRESS,
	S_PHONE,
	S_COMMENT
FROM	PART,
	SUPPLIER,
	PARTSUPP,
	NATION,
	REGION
WHERE	P_PARTKEY	= PS_PARTKEY AND
	S_SUPPKEY	= PS_SUPPKEY AND
	P_SIZE		= 34 AND
	P_TYPE		LIKE '%COPPER' AND
	S_NATIONKEY	= N_NATIONKEY AND
	N_REGIONKEY	= R_REGIONKEY AND
	R_NAME		= 'MIDDLE EAST' AND
	PS_SUPPLYCOST	= (	SELECT	MIN(PS_SUPPLYCOST)
				FROM	PARTSUPP,
					SUPPLIER,
					NATION,
					REGION
				WHERE	P_PARTKEY	= PS_PARTKEY AND
					S_SUPPKEY	= PS_SUPPKEY AND
					S_NATIONKEY	= N_NATIONKEY AND
					N_REGIONKEY	= R_REGIONKEY AND
					R_NAME		= 'MIDDLE EAST'
			  )
ORDER	BY	S_ACCTBAL DESC,
		N_NAME,
		S_NAME,
		P_PARTKEY
;

The salesanalyst user can successfully read data from the region table of the sales schema.

select * from sales.region;

In the following example, the salesanalyst user wants to update the comment for Region key 0 and Region name AFRICA in the region table. But the command fails with a permission denied error because they only have select permission on the region table in the sales schema.

update sales.region
set r_comment = 'Comment from Africa'
where r_regionkey = 0;

The salesanalyst user also wants to access objects from the marketing schema, but the command fails with a permission denied error.

select * from marketing.region;

Example 2: Data read/write task

In this example, the sales engineer who is responsible for building the extract, transform, and load (ETL) pipeline for data processing in the sales schema is given read and write access to perform their tasks. For these steps, we use the dbadmin user unless otherwise mentioned.

  1. Let’s create the read/write role (sales_rw) in the sales schema:
    create role sales_rw;

  2. Create a database user named salesengineer:
    create user salesengineer password 'Test12345';

  3. Grant the sales schema usage and select access to objects of the sales schema to the read/write role by assigning the read-only role to it:
    grant role sales_ro to role sales_rw;

  4. Now assign the user salesengineer to the read/write sales role:
    grant role sales_rw to salesengineer;

Now the salesengineer database user can access the sales schema in the Amazon Redshift database using the salesengineer credentials.

The salesengineer user can successfully read data from the region table of the sales schema.

select * from sales.region;

However, they can’t read tables from the marketing schema because the salesengineer user doesn’t have permission.

select * from marketing.region;

The salesengineer user then tries to update the region table in the sales schema but fails to do so.

update sales.region
set r_comment = 'Comment from Africa'
where r_regionkey = 0;

  1. Now, grant additional insert, update, and delete privileges to the read/write role:
grant update, insert, delete on all tables in schema sales to role sales_rw;

The salesengineer user then retries to update the region table in the sales schema and is able to do so successfully.

update sales.region
set r_comment = 'Comment from Africa'
where r_regionkey = 0;


When they read the data, it shows that the comment was updated for Region key 0 (for AFRICA) in the region table in the sales schema.

select * from sales.region;

Now salesengineer wants to analyze the region table since it was updated. However, they can’t do so, because this user doesn’t have the necessary privileges and isn’t the owner of the region table in the sales schema.

analyze sales.region;

Finally, the salesengineer user wants to vacuum the region table since it was updated. However, they can’t do so because they don’t have the necessary privileges and aren’t the owner of the region table.

vacuum sales.region;

Example 3: Database administration task

Amazon Redshift automatically sorts data and runs VACUUM DELETE in the background.

Similarly, Amazon Redshift continuously monitors your database and automatically performs analyze operations in the background. In some situations, such as a major one-off data load, the database administrator may want to perform maintenance on objects in the sales and marketing schemas immediately. They access the database using dbadmin credentials to perform these tasks.

The dbadmin database user can access the Amazon Redshift database using their credentials to perform analyze and vacuum of the region table in the sales schema.

analyze sales.region;

Vacuum sales.region;


Now the dbadmin database user accesses the Amazon Redshift database to perform analyze and vacuum of the region table in the marketing schema.

analyze marketing.region;

vacuum marketing.region;


As part of developing the ETL process, the salesengineer user needs to truncate the region table in the sales schema. However, they can’t perform a truncate because they don’t have the necessary privileges, and aren’t the owner of the region table in the sales schema.

truncate sales.region;


The dbadmin database user can access the Amazon Redshift database to provide truncate table privileges to the sales_rw role.

grant truncate table to role sales_rw;

Now the salesengineer can perform a truncate on the region table in the sales schema successfully.

First, they read the data:

select * from sales.region;


Then they perform the truncate:

truncate sales.region;


They read the data again to see the changes:

select * from sales.region;


For the marketing schema, you must perform similar operations for the marketing analyst and marketing engineer. We include the following scripts for your reference. The dbadmin user can use the following SQL commands to create the marketing roles and database users, assign privileges to those roles, and attach the users to the roles.

create role marketing_ro;

create role marketing_rw;

grant usage on schema marketing to role marketing_ro, role marketing_rw;

grant select on all tables in schema marketing to role marketing_ro;

grant role marketing_ro to role marketing_rw;

grant insert, update, delete on all tables in schema marketing to role marketing_rw;

create user marketinganalyst password 'Test12345';

create user marketingengineer password 'Test12345';

grant role marketing_ro to  marketinganalyst;

grant role marketing_rw to  marketingengineer;

System functions for RBAC in Amazon Redshift

Amazon Redshift has introduced two new functions to provide system information about particular user membership and role membership in additional groups or roles: role_is_member_of and user_is_member_of. These functions are available to superusers as well as regular users. Superusers can check all role memberships, whereas regular users can only check membership for roles that they have been granted access to.

role_is_member_of(role_name, granted_role_name)

The role_is_member_of function returns true if the role is a member of another role. Superusers can check all roles memberships; regular users can only check roles to which they have access. You receive an error if the provided roles don’t exist or the current user doesn’t have access to them. The following two role memberships are checked using the salesengineer user credentials:

select role_is_member_of('sales_rw', 'sales_ro');

select role_is_member_of('sales_ro', 'sales_rw');

user_is_member_of( user_name, role_or_group_name)

The user_is_member_of function returns true if the user is a member of the specified role or group. Superusers can check all user memberships; regular users can only check their own membership. You receive an error if the provided identities don’t exist or the current user doesn’t have access to them. The following user membership is checked using the salesengineer user credentials, and fails because salesengineer doesn’t have access to salesanalyst:

select user_is_member_of('salesanalyst', 'sales_ro');


When the same user membership is checked using the superuser credential, it returns a result:

select user_is_member_of('salesanalyst', 'sales_ro');

When salesengineer checks their own user membership, it returns the correct results:

select user_is_member_of('salesengineer', 'sales_ro');

select user_is_member_of('salesengineer', 'marketing_ro');

select user_is_member_of('marketinganalyst', 'sales_ro');

System views for RBAC in Amazon Redshift

Amazon Redshift has added several new views to be able to view the roles, the assignment of roles to users, the role hierarchy, and the privileges for database objects via roles. These views are available to superusers as well as regular users. Superusers can check all role details, whereas regular users can only check details for roles that they have been granted access to.

For example, you can query svv_user_grants to view the list of users that are explicitly granted roles in the cluster, or query svv_role_grants to view a list of roles that are explicitly granted roles in the cluster. For the full list of system views, refer to SVV views.

Conclusion

In this post, we demonstrated how you can use role-based access control to further fortify your security posture by granularizing privileged access across users without needing to centralize superuser privileges in your Amazon Redshift cluster. Try out using database roles for your future Amazon Redshift implementations, and feel free to leave a comment about your experience.

In the future posts, we will show how these roles also integrate tightly with workload management. You can use them when defining WLM queues, and also while implementing single sign-on via identity federation with Microsoft Active Directory or a standards-based identity provider, such as Okta Universal Directory or Azure AD and other SAML-based applications.


About the Authors

Milind Oke is a Data Warehouse Specialist Solutions Architect based out of New York. He has been building data warehouse solutions for over 15 years and specializes in Amazon Redshift.

Dipankar Kushari is a Sr. Specialist Solutions Architect, Analytics with AWS.

Harshida Patel is a Specialist Sr. Solutions Architect, Analytics with AWS.

Debu Panda is a Senior Manager, Product Management with AWS. He is an industry leader in analytics, application platform, and database technologies, and has more than 25 years of experience in the IT world. Debu has published numerous articles on analytics, enterprise Java, and databases and has presented at multiple conferences such as re:Invent, Oracle Open World, and Java One. He is lead author of the EJB 3 in Action (Manning Publications 2007, 2014) and Middleware Management (Packt).

Huiyuan Wang is a software development engineer of Amazon Redshift. She has been working on MPP databases for over 6 years and has focused on query processing, optimization and metadata security.

What to consider when migrating data warehouse to Amazon Redshift

Post Syndicated from Lewis Tang original https://aws.amazon.com/blogs/big-data/what-to-consider-when-migrating-data-warehouse-to-amazon-redshift/

Customers are migrating data warehouses to Amazon Redshift because it’s fast, scalable, and cost-effective. However, data warehouse migration projects can be complex and challenging. In this post, I help you understand the common drivers of data warehouse migration, migration strategies, and what tools and services are available to assist with your migration project.

Let’s first discuss the big data landscape, the meaning of a modern data architecture, and what you need to consider for your data warehouse migration project when building a modern data architecture.

Business opportunities

Data is changing the way we work, live, and play. All of this behavior change and the movement to the cloud has resulted in a data explosion over the past 20 years. The proliferation of Internet of Things and smart phones have accelerated the amount of the data that is generated every day. Business models have shifted, and so have the needs of the people running these businesses. We have moved from talking about terabytes of data just a few years ago to now petabytes and exabytes of data. By putting data to work efficiently and building deep business insights from the data collected, businesses in different industries and of various sizes can achieve a wide range of business outcomes. These can be broadly categorized into the following core business outcomes:

  • Improving operational efficiency – By making sense of the data collected from various operational processes, businesses can improve customer experience, increase production efficiency, and increase sales and marketing agility
  • Making more informed decisions – Through developing more meaningful insights by bringing together full picture of data across an organization, businesses can make more informed decisions
  • Accelerating innovation – Combining internal and external data sources enable a variety of AI and machine learning (ML) use cases that help businesses automate processes and unlock business opportunities that were either impossible to do or too difficult to do before

Business challenges

Exponential data growth has also presented business challenges.

First of all, businesses need to access all data across the organization, and data may be distributed in silos. It comes from a variety of sources, in a wide range of data types and in large volume and velocity. Some data may be stored as structured data in relational databases. Other data may be stored as semi-structured data in object stores, such as media files and the clickstream data that is constantly streaming from mobile devices.

Secondly, to build insights from data, businesses need to dive deep into the data by conducting analytics. These analytics activities generally involve dozens and hundreds of data analysts who need to access the system simultaneously. Having a performant system that is scalable to meet the query demand is often a challenge. It gets more complex when businesses need to share the analyzed data with their customers.

Last but not least, businesses need a cost-effective solution to address data silos, performance, scalability, security, and compliance challenges. Being able to visualize and predict cost is necessary for a business to measure the cost-effectiveness of its solution.

To solve these challenges, businesses need a future proof modern data architecture and a robust, efficient analytics system.

Modern data architecture

A modern data architecture enables organizations to store any amount of data in open formats, break down disconnected data silos, empower users to run analytics or ML using their preferred tool or technique, and manage who has access to specific pieces of data with the proper security and data governance controls.

The AWS data lake architecture is a modern data architecture that enables you to store data in a data lake and use a ring of purpose-built data services around the lake, as shown in the following figure. This allows you to make decisions with speed and agility, at scale, and cost-effectively. For more details, refer to Modern Data Architecture on AWS.

Modern data warehouse

Amazon Redshift is a fully managed, scalable, modern data warehouse that accelerates time to insights with fast, easy, and secure analytics at scale. With Amazon Redshift, you can analyze all your data and get performance at any scale with low and predictable costs.

Amazon Redshift offers the following benefits:

  • Analyze all your data – With Amazon Redshift, you can easily analyze all your data across your data warehouse and data lake with consistent security and governance policies. We call this the modern data architecture. With Amazon Redshift Spectrum, you can query data in your data lake with no need for loading or other data preparation. And with data lake export, you can save the results of an Amazon Redshift query back into the lake. This means you can take advantage of real-time analytics and ML/AI use cases without re-architecture, because Amazon Redshift is fully integrated with your data lake. With new capabilities like data sharing, you can easily share data across Amazon Redshift clusters both internally and externally, so everyone has a live and consistent view of the data. Amazon Redshift ML makes it easy to do more with your data—you can create, train, and deploy ML models using familiar SQL commands directly in Amazon Redshift data warehouses.
  • Fast performance at any scale – Amazon Redshift is a self-tuning and self-learning system that allows you to get the best performance for your workloads without the undifferentiated heavy lifting of tuning your data warehouse with tasks such as defining sort keys and distribution keys, and new capabilities like materialized views, auto-refresh, and auto-query rewrite. Amazon Redshift scales to deliver consistently fast results from gigabytes to petabytes of data, and from a few users to thousands. As your user base scales to thousands of concurrent users, the concurrency scaling capability automatically deploys the necessary compute resources to manage the additional load. Amazon Redshift RA3 instances with managed storage separate compute and storage, so you can scale each independently and only pay for the storage you need. AQUA (Advanced Query Accelerator) for Amazon Redshift is a new distributed and hardware-accelerated cache that automatically boosts certain types of queries.
  • Easy analytics for everyone – Amazon Redshift is a fully managed data warehouse that abstracts away the burden of detailed infrastructure management or performance optimization. You can focus on getting to insights, rather than performing maintenance tasks like provisioning infrastructure, creating backups, setting up the layout of data, and other tasks. You can operate data in open formats, use familiar SQL commands, and take advantage of query visualizations available through the new Query Editor v2. You can also access data from any application through a secure data API without configuring software drivers, managing database connections. Amazon Redshift is compatible with business intelligence (BI) tools, opening up the power and integration of Amazon Redshift to business users who operate from within the BI tool.

A modern data architecture with a data lake architecture and modern data warehouse with Amazon Redshift helps businesses in all different sizes address big data challenges, make sense of a large amount of data, and drive business outcomes. You can start the journey of building a modern data architecture by migrating your data warehouse to Amazon Redshift.

Migration considerations

Data warehouse migration presents a challenge in terms of project complexity and poses a risk in terms of resources, time, and cost. To reduce the complexity of data warehouse migration, it’s essential to choose a right migration strategy based on your existing data warehouse landscape and the amount of transformation required to migrate to Amazon Redshift. The following are the key factors that can influence your migration strategy decision:

  • Size – The total size of the source data warehouse to be migrated is determined by the objects, tables, and databases that are included in the migration. A good understanding of the data sources and data domains required for moving to Amazon Redshift leads to an optimal sizing of the migration project.
  • Data transfer – Data warehouse migration involves data transfer between the source data warehouse servers and AWS. You can either transfer data over a network interconnection between the source location and AWS such as AWS Direct Connect or transfer data offline via the tools or services such as the AWS Snow Family.
  • Data change rate – How often do data updates or changes occur in your data warehouse? Your existing data warehouse data change rate determines the update intervals required to keep the source data warehouse and the target Amazon Redshift in sync. A source data warehouse with a high data change rate requires the service switching from the source to Amazon Redshift to complete within an update interval, which leads to a shorter migration cutover window.
  • Data transformation – Moving your existing data warehouse to Amazon Redshift is a heterogenous migration involving data transformation such as data mapping and schema change. The complexity of data transformation determines the processing time required for an iteration of migration.
  • Migration and ETL tools – The selection of migration and extract, transform, and load (ETL) tools can impact the migration project. For example, the efforts required for deployment and setup of these tools can vary. We look closer at AWS tools and services shortly.

After you have factored in all these considerations, you can pick a migration strategy option for your Amazon Redshift migration project.

Migration strategies

You can choose from three migration strategies: one-step migration, two-step migration, or wave-based migration.

One-step migration is a good option for databases that don’t require continuous operation such as continuous replication to keep ongoing data changes in sync between the source and destination. You can extract existing databases as comma separated value (CSV) files, or columnar format like Parquet, then use AWS Snow Family services such as AWS Snowball to deliver datasets to Amazon Simple Storage Service (Amazon S3) for loading into Amazon Redshift. You then test the destination Amazon Redshift database for data consistency with the source. After all validations have passed, the database is switched over to AWS.

Two-step migration is commonly used for databases of any size that require continuous operation, such as the continuous replication. During the migration, the source databases have ongoing data changes, and continuous replication keeps data changes in sync between the source and Amazon Redshift. The breakdown of the two-step migration strategy is as follows:

  • Initial data migration – The data is extracted from the source database, preferably during non-peak usage to minimize the impact. The data is then migrated to Amazon Redshift by following the one-step migration approach described previously.
  • Changed data migration – Data that changed in the source database after the initial data migration is propagated to the destination before switchover. This step synchronizes the source and destination databases. After all the changed data is migrated, you can validate the data in the destination database and perform necessary tests. If all tests are passed, you then switch over to the Amazon Redshift data warehouse.

Wave-based migration is suitable for large-scale data warehouse migration projects. The principle of wave-based migration is taking precautions to divide a complex migration project into multiple logical and systematic waves. This strategy can significantly reduce the complexity and risk. You start from a workload that covers a good number of data sources and subject areas with medium complexity, then add more data sources and subject areas in each subsequent wave. With this strategy, you run both the source data warehouse and Amazon Redshift production environments in parallel for a certain amount of time before you can fully retire the source data warehouse. See Develop an application migration methodology to modernize your data warehouse with Amazon Redshift for details on how to identify and group data sources and analytics applications to migrate from the source data warehouse to Amazon Redshift using the wave-based migration approach.

To guide your migration strategy decision, refer to the following table to map the consideration factors with a preferred migration strategy.

. One-Step Migration Two-Step Migration Wave-Based Migration
The number of subject areas in migration scope Small Medium to Large Medium to Large
Data transfer volume Small to Large Small to Large Small to Large
Data change rate during migration None Minimal to Frequent Minimal to Frequent
Data transformation complexity Any Any Any
Migration change window for switching from source to target Hours Seconds Seconds
Migration project duration Weeks Weeks to Months Months

Migration process

In this section, we review the three high-level steps of the migration process. The two-step migration strategy and wave-based migration strategy involve all three migration steps. However, the wave-based migration strategy includes a number of iterations. Because only databases that don’t require continuous operations are good fits for one-step migration, only Steps 1 and 2 in the migration process are required.

Step 1: Convert schema and subject area

In this step, you make the source data warehouse schema compatible with the Amazon Redshift schema by converting the source data warehouse schema using schema conversion tools such as AWS Schema Conversion Tool (AWS SCT) and the other tools from AWS partners. In some situations, you may also be required to use custom code to conduct complex schema conversions. We dive deeper into AWS SCT and migration best practices in a later section.

Step 2: Initial data extraction and load

In this step, you complete the initial data extraction and load the source data into Amazon Redshift for the first time. You can use AWS SCT data extractors to extract data from the source data warehouse and load data to Amazon S3 if your data size and data transfer requirements allow you to transfer data over the interconnected network. Alternatively, if there are limitations such as network capacity limit, you can load data to Snowball and from there data gets loaded to Amazon S3. When the data in the source data warehouse is available on Amazon S3, it’s loaded to Amazon Redshift. In situations when the source data warehouse native tools do a better data unload and load job than AWS SCT data extractors, you may choose to use the native tools to complete this step.

Step 3: Delta and incremental load

In this step, you use AWS SCT and sometimes source data warehouse native tools to capture and load delta or incremental changes from sources to Amazon Redshift. This is often referred to change data capture (CDC). CDC is a process that captures changes made in a database, and ensures that those changes are replicated to a destination such as a data warehouse.

You should now have enough information to start developing a migration plan for your data warehouse. In the following section, I dive deeper into the AWS services that can help you migrate your data warehouse to Amazon Redshift, and the best practices of using these services to accelerate a successful delivery of your data warehouse migration project.

Data warehouse migration services

Data warehouse migration involves a set of services and tools to support the migration process. You begin with creating a database migration assessment report and then converting the source data schema to be compatible with Amazon Redshift by using AWS SCT. To move data, you can use the AWS SCT data extraction tool, which has integration with AWS Data Migration Service (AWS DMS) to create and manage AWS DMS tasks and orchestrate data migration.

To transfer source data over the interconnected network between the source and AWS, you can use AWS Storage Gateway, Amazon Kinesis Data Firehose, Direct Connect, AWS Transfer Family services, Amazon S3 Transfer Acceleration, and AWS DataSync. For data warehouse migration involving a large volume of data, or if there are constraints with the interconnected network capacity, you can transfer data using the AWS Snow Family of services. With this approach, you can copy the data to the device, send it back to AWS, and have the data copied to Amazon Redshift via Amazon S3.

AWS SCT is an essential service to accelerate your data warehouse migration to Amazon Redshift. Let’s dive deeper into it.

Migrating using AWS SCT

AWS SCT automates much of the process of converting your data warehouse schema to an Amazon Redshift database schema. Because the source and target database engines can have many different features and capabilities, AWS SCT attempts to create an equivalent schema in your target database wherever possible. If no direct conversion is possible, AWS SCT creates a database migration assessment report to help you convert your schema. The database migration assessment report provides important information about the conversion of the schema from your source database to your target database. The report summarizes all the schema conversion tasks and details the action items for schema objects that can’t be converted to the DB engine of your target database. The report also includes estimates of the amount of effort that it will take to write the equivalent code in your target database that can’t be converted automatically.

Storage optimization is the heart of a data warehouse conversion. When using your Amazon Redshift database as a source and a test Amazon Redshift database as the target, AWS SCT recommends sort keys and distribution keys to optimize your database.

With AWS SCT, you can convert the following data warehouse schemas to Amazon Redshift:

  • Amazon Redshift
  • Azure Synapse Analytics (version 10)
  • Greenplum Database (version 4.3 and later)
  • Microsoft SQL Server (version 2008 and later)
  • Netezza (version 7.0.3 and later)
  • Oracle (version 10.2 and later)
  • Snowflake (version 3)
  • Teradata (version 13 and later)
  • Vertica (version 7.2 and later)

At AWS, we continue to release new features and enhancements to improve our product. For the latest supported conversions, visit the AWS SCT User Guide.

Migrating data using AWS SCT data extraction tool

You can use an AWS SCT data extraction tool to extract data from your on-premises data warehouse and migrate it to Amazon Redshift. The agent extracts your data and uploads the data to either Amazon S3 or, for large-scale migrations, an AWS Snowball Family service. You can then use AWS SCT to copy the data to Amazon Redshift. Amazon S3 is a storage and retrieval service. To store an object in Amazon S3, you upload the file you want to store to an S3 bucket. When you upload a file, you can set permissions on the object and also on any metadata.

In large-scale migrations involving data upload to a AWS Snowball Family service, you can use wizard-based workflows in AWS SCT to automate the process in which the data extraction tool orchestrates AWS DMS to perform the actual migration.

Considerations for Amazon Redshift migration tools

To improve and accelerate data warehouse migration to Amazon Redshift, consider the following tips and best practices. Tthis list is not exhaustive. Make sure you have a good understanding of your data warehouse profile and determine which best practices you can use for your migration project.

  • Use AWS SCT to create a migration assessment report and scope migration effort.
  • Automate migration with AWS SCT where possible. The experience from our customers shows that AWS SCT can automatically create the majority of DDL and SQL scripts.
  • When automated schema conversion is not possible, use custom scripting for the code conversion.
  • Install AWS SCT data extractor agents as close as possible to the data source to improve data migration performance and reliability.
  • To improve data migration performance, properly size your Amazon Elastic Compute Cloud (Amazon EC2) instance and its equivalent virtual machines that the data extractor agents are installed on.
  • Configure multiple data extractor agents to run multiple tasks in parallel to improve data migration performance by maximizing the usage of the allocated network bandwidth.
  • Adjust AWS SCT memory configuration to improve schema conversion performance.
  • Use Amazon S3 to store the large objects such as images, PDFs, and other binary data from your existing data warehouse.
  • To migrate large tables, use virtual partitioning and create sub-tasks to improve data migration performance.
  • Understand the use cases of AWS services such as Direct Connect, the AWS Transfer Family, and the AWS Snow Family. Select the right service or tool to meet your data migration requirements.
  • Understand AWS service quotas and make informed migration design decisions.

Summary

Data is growing in volume and complexity faster than ever. However, only a fraction of this invaluable asset is available for analysis. Traditional on-premises data warehouses have rigid architectures that don’t scale for modern big data analytics use cases. These traditional data warehouses are expensive to set up and operate, and require large upfront investments in both software and hardware.

In this post, we discussed Amazon Redshift as a fully managed, scalable, modern data warehouse that can help you analyze all your data, and achieve performance at any scale with low and predictable cost. To migrate your data warehouse to Amazon Redshift, you need to consider a range of factors, such as the total size of the data warehouse, data change rate, and data transformation complexity, before picking a suitable migration strategy and process to reduce the complexity and cost of your data warehouse migration project. With AWS services such AWS SCT and AWS DMS, and by adopting the tips and the best practices of these services, you can automate migration tasks, scale migration, accelerate the delivery of your data warehouse migration project, and delight your customers.


About the Author

Lewis Tang is a Senior Solutions Architect at Amazon Web Services based in Sydney, Australia. Lewis provides partners guidance to a broad range of AWS services and help partners to accelerate AWS practice growth.

Federated access to Amazon Redshift clusters in AWS China Regions with Active Directory Federation Services

Post Syndicated from Clement Yuan original https://aws.amazon.com/blogs/big-data/federated-access-to-amazon-redshift-clusters-in-aws-china-regions-with-active-directory-federation-services/

Many customers already manage user identities through identity providers (IdPs) for single sign-on access. With an IdP such as Active Directory Federation Services (AD FS), you can set up federated access to Amazon Redshift clusters as a mechanism to control permissions for the database objects by business groups. This provides a seamless user experience, and centralizes the governance of authentication and permissions for end-users. For more information, refer to the blog post series “Federate access to your Amazon Redshift cluster with Active Directory Federation Services (AD FS)” (part 1, part 2).

Due to the differences in the implementation of Amazon Web Services in China, customers have to adjust the configurations accordingly. For example, AWS China Regions (Beijing and Ningxia) are in a separate AWS partition, therefore all the Amazon Resource Names (ARNs) include the suffix -cn. AWS China Regions are also hosted at a different domain: www.amazonaws.cn.

This post introduces a step-by-step procedure to set up federated access to Amazon Redshift in AWS China Regions. It pinpoints the key differences you should pay attention to and provides a troubleshooting guide for common errors.

Solution overview

The following diagram illustrates the process of Security Assertion Markup Language 2.0 (SAML)-based federation access to Amazon Redshift in AWS China Regions. The workflow includes the following major steps:

  1. The SQL client provides a user name and password to AD FS.
  2. AD FS authenticates the credential and returns a SAML response if successful.
  3. The SQL client makes an API call to AWS Security Token Service (AWS STS) to assume a preferred role with SAML.
  4. AWS STS authenticates the SAML response based on the mutual trust and returns temporary credentials if successful.
  5. The SQL client communicates with Amazon Redshift to get back a database user with temporary credentials, then uses it to join database groups and connect to the specified database.

The architecture

We organize the walkthrough in the following high-level steps:

  1. Configure an AD FS relying party trust for AWS China Regions and define basic claim rules.
  2. Provision an AWS Identity and Access Management (IAM) identity provider and roles.
  3. Complete the remaining relying party trust’s claim rules based on the IAM resources.
  4. Connect to Amazon Redshift with federated access via a JDBC-based SQL client.

Prerequisites

This post assumes that you have the following prerequisites:

  • Windows Server 2016
  • The ability to create users and groups in AD
  • The ability to configure a relying party trust and define claim rules in AD FS
  • An AWS account
  • Sufficient permissions to provision IAM identity providers, roles, Amazon Virtual Private Cloud (Amazon VPC) related resources, and an Amazon Redshift cluster via AWS Cloud Development Kit (AWS CDK)

Configure an AD FS relying party trust and define claim rules

A relying party trust allows AWS and AD FS to communicate with each other. It is possible to configure two relying party trusts for both AWS China Regions and AWS Regions in the same AD FS at the same time. For AWS China Regions, we need to use a different SAML metadata document at https://signin.amazonaws.cn/static/saml-metadata.xml. The relying party’s identifier for AWS China Regions is urn:amazon:webservices:cn-north-1, whereas that for AWS Global Regions is urn:amazon:webservices. Note down this identifier to use later in this post.

Relying party metadata XML

Add AD groups and users

With SAML-based federation, end-users assume an IAM role and use it to join multiple database (DB) groups. The permissions on such roles and DB groups can be effectively managed by AD groups. We use different prefixes in AD group names to distinguish them, which help map to roles and DB group claim rules. It’s important to distinguish correctly the two types of AD groups because they’re mapped to different AWS resources.

We continue our walkthrough with an example. Suppose in business there are two roles: data scientist and data engineer, and two DB groups: oncology and pharmacy. Data scientists can join both groups, and data engineers can only join the pharmacy group. On the AD side, we define one AD group for each role and group. On the AWS side, we define one IAM role for each role and one Amazon Redshift DB group for each DB group. Suppose Clement is a data scientist and Jimmy is a data engineer, and both are already managed by AD. The following diagram illustrates this relationship.

AD group and user mapping to IAM role and DB group

You may create the AD groups and users with either the AWS Command Line Interface (AWS CLI) or the AWS Management Console. We provide sample commands in the README file in the GitHub repo.

Follow substeps a to o of Step 2 in Setting up JDBC or ODBC Single Sign-on authentication with AD FS to set up the relying party with the correct SAML metadata document for AWS China Regions and define the first three claim rules (NameId, RoleSessionName, and Get AD Groups). We resume after the IAM identity provider and roles are provisioned.

Provision an IAM identity provider and roles

You establish the trust for AD with AWS by provisioning an IAM identity provider. The IAM identity provider and assumed roles should be in one AWS account, otherwise you get the following error message during federated access: “Principal exists outside the account of the Role being assumed.” Follow these steps to provision the resources:

  1. Download the metadata file at https://yourcompany.com/FederationMetadata/2007-06/FederationMetadata.xml from your AD FS server.
  2. Save it locally at /tmp/FederationMetadata.xml.
  3. Check out the AWS CDK code on GitHub.
  4. Use AWS CDK to deploy the stack named redshift-cn:
export AWS_ACCOUNT=YOUR_AWS_ACCOUNT
export AWS_DEFAULT_REGION=cn-north-1
export AWS_PROFILE=YOUR_PROFILE

cdk deploy redshift-cn --require-approval never

The AWS CDK version should be 2.0 or newer. For testing purposes, you may use the AdministratorAccess managed policy for the deployment. For production usage, use a profile with least privilege.

The following table summarizes the resources that the AWS CDK package provisions.

Service Resource Count Notes
Amazon VPC VPC 1 .
Subnet 2 .
Internet gateway 1 .
Route table 1 .
Security group 1 .
IAM SAML Identity provider 1 .
Role 3 1 service role for cluster
2 federated roles
Amazon Redshift Cluster 1 1 node, dc2.large
AWS Secrets Manager Secret 1 .

In this example, the Publicly Accessible setting of the Amazon Redshift cluster is set to Enabled for simplicity. However, in a production environment, you should disable this setting and place the cluster inside a private subnet group. Refer to How can I access a private Amazon Redshift cluster from my local machine for more information.

Configure a security group

Add an inbound rule for your IP address to allow connection to the Amazon Redshift cluster.

  1. Find the security group named RC Default Security Group.
  2. Obtain the pubic IP address of your machine.
  3. Add an inbound rule for this IP address and the default port for Amazon Redshift 5439.

Complete the remaining claim rules

After you provision the IAM identity provider and roles, add a claim rule to define SAML roles. We add a customer claim rule with the name Roles. It finds AD groups with the prefix role_ and replaces it with a combined ARN string. Pay attention to the ARNs of the resources where the partition is aws-cn. Replace AWS_ACCOUNT with your AWS account ID. The following table demonstrates how the selected AD groups are transformed to IAM role ARNs.

Selected AD Group Transformed IAM Role ARN
role_data_scientist arn:aws-cn:iam::AWS_ACCOUNT:role/rc_data_scientist
role_data_engineer arn:aws-cn:iam::AWS_ACCOUNT:role/rc_data_engineer

Relying party claim rule

To add the claim rule, open the AD FS management console in your Windows Server and complete the following steps:

  1. Choose Relying Party Trusts, then choose the relying party for AWS China.
  2. Choose Edit Claim Issuance Policy, then choose Add Role.
  3. On the Claim rule template menu, choose Send Claims Using a Custom Rule.
  4. For Claim rule name, enter Roles.
  5. In the Custom rule section, enter the following:
c:[Type == "http://temp/variable", Value =~ "(?i)^role_"]
=> issue(Type = "https://aws.amazon.com/SAML/Attributes/Role",
Value = RegExReplace(c.Value, "role_",
"arn:aws-cn:iam::AWS_ACCOUNT:saml-provider/rc-provider,arn:aws-cn:iam::AWS_ACCOUNT:role/rc_"));

The optional parameters of DbUser, AutoCreate, and DbGroups can be provided via either JDBC connection parameters or SAML attribute values. The benefit of user federation is to manage users in one place centrally. Therefore, the DbUser value should be automatically provided by the SAML attribute. The AutoCreate parameter should always be true, otherwise you have to create DB users beforehand. Finally, the DbGroups parameter could be provided by SAML attributes provided that such relationship is defined in AD.

To summarize, we recommend to provide at least DbUser and AutoCreate in SAML attributes, such that the end-user can save time by composing shorter connection strings. In our example, we provide all three parameters via SAML attributes.

  1. Add a customer claim rule named DbUser. We use an email address as the value for DbUser:
c:[Type == "http://schemas.microsoft.com/ws/2008/06/identity/claims/windowsaccountname", 
 Issuer == "AD AUTHORITY"]
=> issue(store = "Active Directory",
types = ("https://redshift.amazon.com/SAML/Attributes/DbUser"),
query = ";mail;{0}", param = c.Value);

You can also choose a Security Accounts Manager (SAM) account name, which is usually the user name of the email address. Using an email address plays an important role in IAM role policy setting. We revisit this issue later.

  1. Add the custom claim rule named AutoCreate:
=> issue(type = "https://redshift.amazon.com/SAML/Attributes/AutoCreate", value = "true");
  1. Add a customer claim rule named DbGroups. It finds all AD groups with the prefix group_ and lists them as values for DbGroups:
c:[Type == "http://temp/variable", Value =~ "(?i)^group_"]
=> issue(Type = "https://redshift.amazon.com/SAML/Attributes/DbGroups", Value = c.Value);

You can test the preceding setting is correct by obtaining the SAML response via your browser.

  1. Visit https://yourcompany.com/adfs/ls/IdpInitiatedSignOn.aspx on your Windows Server, log in with user clement, and check that the following SAML attributes exist. For user jimmy, the role is rc_data_engineer and the DB group contains only group_pharmacy.
<AttributeStatement>
    <Attribute Name="https://aws.amazon.com/SAML/Attributes/RoleSessionName">
        <AttributeValue>[email protected]</AttributeValue>
    </Attribute>
    <Attribute Name="https://aws.amazon.com/SAML/Attributes/Role">
        <AttributeValue>arn:aws-cn:iam::AWS_ACCOUNT:saml-provider/rc-provider,arn:aws-cn:iam::AWS_ACCOUNT:role/rc_data_scientist</AttributeValue>
    </Attribute>
    <Attribute Name="https://redshift.amazon.com/SAML/Attributes/DbUser">
        <AttributeValue>[email protected]</AttributeValue>
    </Attribute>
    <Attribute Name="https://redshift.amazon.com/SAML/Attributes/AutoCreate">
        <AttributeValue>true</AttributeValue>
    </Attribute>
    <Attribute Name="https://redshift.amazon.com/SAML/Attributes/DbGroups">
        <AttributeValue>group_pharmacy</AttributeValue>
        <AttributeValue>group_oncology</AttributeValue>
    </Attribute>
</AttributeStatement>

The preceding SAML attribute names are verified valid for AWS China Regions. The URLs end with amazon.com. It’s incorrect to change them to amazonaws.cn or amazon.cn.

Connect to Amazon Redshift with a SQL client

We use JDBC-based SQL Workbench/J (SQL client) to connect to the Amazon Redshift cluster. Amazon Redshift uses a DB group to collect DB users. The database privileges are managed collectively at group level. In this post, we don’t dive deep into privilege management. However, you need to create the preceding two DB groups.

  1. Connect to the provisioned cluster and create the groups. You can connect on the AWS Management Console via the query editor with temporary credentials, or via a SQL client with database user admin and password. The password is stored in AWS Secrets Manager. You may need proper permissions for the above operations.
create group group_oncology;
create group group_pharmacy;
  1. Follow the instructions in Connect to your cluster by using SQL Workbench/J to download and install the SQL client and the Amazon Redshift JDBC driver.

We recommend the JDBC driver version 2.1 with AWS SDK driver-dependent libraries.

  1. Test that the cluster is connectable via its endpoint. The primary user name is admin. You retrieve the secret value of the cluster’s password via Secrets Manager. Specify DSILogLevel and LogPath to collect driver logs and help diagnosis. The connection string looks like the following code. Replace CLUSTER_ENDPOINT with the correct value and delete all line breakers. We split the line for readability.
jdbc:redshift://CLUSTER_ENDPOINT.cn-north-1.redshift.amazonaws.com.cn:5439/main
;ssl_insecure=true
;DSILogLevel=3
;LogPath=/tmp

For AWS China Regions, one extra JDBC driver option loginToRp must be set as you set up a separate relying party trust for the AWS China Regions. If an AD user is mapped to more than one AWS role, in the connection string, use preferred_role to specify the exact role to assume for federated access.

  1. Copy the role ARN directly and pay attention to the aws-cn partition.

If the user is mapped to only one role, this option can be omitted.

  1. Replace CLUSTER_ID with the correct cluster identifier. For the user name, enter yourcompany\clement; for the password, enter the credential from AD:
jdbc:redshift:iam://CLUSTER_ID:cn-north-1/main
;ssl_insecure=true
;DSILogLevel=3
;LogPath=/tmp
;loginToRp=urn:amazon:webservices:cn-north-1
;plugin_name=com.amazon.redshift.plugin.AdfsCredentialsProvider
;idp_host=adfsserver.yourcompany.com
;preferred_role=arn:aws-cn:iam::AWS_ACCOUNT:role/rc_data_scientist
  1. When you’re connected, run the SQL statement as shown in the following screenshot.

The user prefixed with IAMA indicates that the user connected with federated access and was auto-created.

SQL Workbench to query users

  1. As an optional step, in the connection string, you can set the DbUser, AutoCreate, and DbGroups parameters.

Parameters from the connection string are before those from SAML attributes. We recommend you set at least DbUser and AutoCreate via SAML attributes. If it’s difficult to manage DB groups in AD users or you want flexibility, specify DbGroups in the connection string. See the following code:

jdbc:redshift:iam://CLUSTER_ID:cn-north-1/main
;ssl_insecure=true
;DSILogLevel=3
;LogPath=/tmp
;loginToRp=urn:amazon:webservices:cn-north-1
;plugin_name=com.amazon.redshift.plugin.AdfsCredentialsProvider
;idp_host=adfsserver.yourcompany.com
;preferred_role=arn:aws-cn:iam::AWS_ACCOUNT:role/rc_data_scientist
;[email protected]
;AutoCreate=true
;DbGroups=group_oncology

Use an email or SAM account name as DB user

The role policy follows the example policy for using GetClusterCredentials. It further allows redshift:DescribeClusters on the cluster because the role queries the cluster endpoint and port based on its identifier and Region. To make sure that the DB user is the same as the AD user, in this post, we use the following condition to check, where ROLE_ID is the unique identifier of the role:

{"StringEqualsIgnoreCase": {"aws:userid": "ROLD_ID:${redshift:DbUser}"}}

The example policy uses the following condition:

{"StringEqualsIgnoreCase": {"aws:userid": "ROLD_ID:${redshift:DbUser}@yourcompany.com"}}

The difference is apparent. The aws:userid contains the RoleSessionName, which is the email address. The SAM account name is the string before @ in the email address. Because the connection string parameter is before the SAML attribute parameter, we summarize the possible cases as follows:

  • If SAML attributes contain DbUser:
    • If the condition value contains a domain suffix:
      • If the DbUser SAML attribute value is an email address, DbUser must be in the connection string without the domain suffix.
      • If the DbUser SAML attribute value is a SAM account name, DbUser can be omitted in the connection string. Otherwise, the value must not contain a domain suffix.
    • If the condition value doesn’t contain a domain suffix:
      • If the DbUser SAML attribute value is an email address, DbUser can be omitted in the connection string. Otherwise, the value must contain a domain suffix.
      • If the DbUser SAML attribute value is a SAM account name, DbUser must be in the connection string with a domain suffix.
  • If SAML attributes don’t contain DbUser:
    • If the condition value contains a domain suffix, DbUser must be in the connection string without a domain suffix.
    • If the condition value doesn’t contain a domain suffix, DbUser can be omitted in the connection string, because RoleSessionName value which is the email address acts as DbUser. Otherwise, the value must contain a domain suffix.

IAM policy condition judgment workflow

Troubleshooting

Federated access to Amazon Redshift is a non-trivial process. However, it consists of smaller steps that we can divide and conquer when problems occur. Refer to the access diagram in the solution overview. We can split the process into three phrases:

  1. Is SAML-based federation successful? Verify this by visiting the single sign-on page of AD FS and make sure you can sign in to the console with the federated role. Do you configure the relying party with the AWS China specific metadata document? Obtain the SAML response and check if the destination is https://signin.amazonaws.cn/saml. Are the SAML provider ARN and IAM role ARNs correct? Check if the role’s trust relationship contains the correct value for SAML:aud. For other possible checkpoints, refer to Troubleshooting SAML 2.0 federation with AWS.
  2. Are the role policies correct? If SAML-based federation is successful, check the role policies are correct. Compare yours with those provided by this post. Did you use aws where aws-cn should be used? If the policy condition contains a domain suffix, is it the correct domain suffix? You can obtain the domain suffix in use if you get the error that the assumed role isn’t authorized to perform an action.
  3. Is the SQL client connecting successfully? Is the cluster identifier correct? Make sure that your connection string contains the loginToRp option and points to the AWS China relying party. If multiple IAM roles are mapped, make sure preferred_role is one of them with the correct role ARN. You can get the list of roles in the SAML response. Try to set ssl_insecure to true temporarily for debugging. Check the previous subsection and make sure the DbUser is properly used or set according to the DbUser SAML attribute and condition value for aws:user. Turn on the driver logs and get debug hints there. Sometimes you may need to restart the SQL client to clear the cache and retry.

Security concerns

In a production environment, we suggest applying the following security settings, which aren’t used in this post.

For the Amazon Redshift cluster, complete the following:

  • Disable the publicly accessible option and place the cluster inside a private or isolated subnet group
  • Encrypt the cluster, for example, with a customer managed AWS Key Management Service (AWS KMS) key
  • Enable enhanced VPC routing such that the network doesn’t leave your VPC
  • Configure the cluster to require Secure Sockets Layer (SSL) and use one-way SSL authentication

For the IAM federated roles:

  • Specify the exact DB groups for action redshift:JoinGroup. If you want to use a wildcard, make sure it doesn’t permit unwanted DB groups.
  • Check StringEquals for aws:user against the role ID along with the Amazon Redshift DB user. This condition can be checked for GetClusterCredentials, CreateClusterUser, and JoinGroup actions. Refer to the sample code for detailed codes.

In Amazon Redshift, the DB group is used to manage privileges for a collection of DB users. A DB user joins some DB groups during a login session and is granted the privileges associated to the groups. As we discussed before, you can use either the SAML attribute value or the connection property to specify the DB groups. The Amazon Redshift driver prefers the value from the connection string to that from the SAML attribute. As a result, the end-user can override the DB groups in the connection string. Therefore, to confine the privileges a DB user can be granted, the IAM role policy must restrict which DB groups the DB user is allowed to join safely, otherwise there might be a security risk. The following policy snippet shows such a risk. Always follow the least privilege principle when defining permission policies.

{
    "Effect": "Allow",
    "Action": "redshift:JoinGroup",
    "Resource": "*"
}

Clean up

Run the following command to destroy the resources and stop incurring charges:

cdk destroy redshift-cn --force

Remove the users and groups created in the AD FS. Finally, remove the relying party trust for AWS China Regions in your AD FS if you don’t need it anymore.

Conclusion

In this post, we walked you through how to connect to Amazon Redshift in China with federated access based on AD FS. AWS China Regions are in a partition different from other AWS Regions, so you must pay special attention during the configuration. In summary, you need to check AWS resources ARNs with the aws-cn partition, SAML-based federation with the AWS China specific metadata document, and an Amazon Redshift JDBC driver with extra connecting options. This post also discusses different usage scenarios for the redshift:Dbuser parameter and provides common troubleshooting suggestions.

For more information, refer to the Amazon Redshift Cluster Management Guide. Find the code used for this post in the following GitHub repository.


About the Authors


Clement YuanWenjun Yuan
is a Cloud Infra Architect in AWS Professional Services based in Chengdu, China. He works with various customers, from startups to international enterprises, helping them build and implement solutions with state-of-the-art cloud technologies and achieve more in their cloud explorations. He enjoys reading poetry and traveling around the world in his spare time.

Khoa NguyễnKhoa Nguyen is a Big Data Architect in AWS Professional Services. He works with large enterprise customers and AWS partners to accelerate customers’ business outcomes by providing expertise in Big Data and AWS services.

Yewei Li is a Data Architect in AWS Professional Services based in Shanghai, China. He works with various enterprise customers to design and build data warehousing and data lake solutions on AWS. In his spare time, he loves reading and doing sports.

Accelerate your data warehouse migration to Amazon Redshift – Part 5

Post Syndicated from Michael Soo original https://aws.amazon.com/blogs/big-data/part-5-accelerate-your-data-warehouse-migration-to-amazon-redshift/

This is the fifth in a series of posts. We’re excited to share dozens of new features to automate your schema conversion; preserve your investment in existing scripts, reports, and applications; accelerate query performance; and potentially simplify your migrations from legacy data warehouses to Amazon Redshift.

Check out the all the posts in this series:

Amazon Redshift is the leading cloud data warehouse. No other data warehouse makes it as easy to gain new insights from your data. With Amazon Redshift, you can query exabytes of data across your data warehouse, operational data stores, and data lake using standard SQL. You can also integrate other AWS services such as Amazon EMR, Amazon Athena, Amazon SageMaker, AWS Glue, AWS Lake Formation, and Amazon Kinesis to use all the analytic capabilities in the AWS Cloud.

Until now, migrating a data warehouse to AWS has been a complex undertaking, involving a significant amount of manual effort. You need to manually remediate syntax differences, inject code to replace proprietary features, and manually tune the performance of queries and reports on the new platform.

Legacy workloads may rely on non-ANSI, proprietary features that aren’t directly supported by modern databases like Amazon Redshift. For example, many Teradata applications use SET tables, which enforce full row uniqueness—there can’t be two rows in a table that are identical in all of their attribute values.

If you’re an Amazon Redshift user, you may want to implement SET semantics but can’t rely on a native database feature. You can use the design patterns in this post to emulate SET semantics in your SQL code. Alternatively, if you’re migrating a workload to Amazon Redshift, you can use the AWS Schema Conversion Tool (AWS SCT) to automatically apply the design patterns as part of your code conversion.

In this post, we describe the SQL design patterns and analyze their performance, and show how AWS SCT can automate this as part of your data warehouse migration. Let’s start by understanding how SET tables behave in Teradata.

Teradata SET tables

At first glance, a SET table may seem similar to a table that has a primary key defined across all of its columns. However, there are some important semantic differences from traditional primary keys. Consider the following table definition in Teradata:

CREATE SET TABLE testschema.sales_by_month (
  sales_dt DATE
, amount DECIMAL(8,2)
);

We populate the table with four rows of data, as follows:

select * from testschema.sales_by_month order by sales_dt;

*** Query completed. 4 rows found. 2 columns returned. 
*** Total elapsed time was 1 second.

sales_dt amount
-------- ----------
22/01/01 100.00
22/01/02 200.00
22/01/03 300.00
22/01/04 400.00

Notice that we didn’t define a UNIQUE PRIMARY INDEX (similar to a primary key) on the table. Now, when we try to insert a new row into the table that is a duplicate of an existing row, the insert fails:

INSERT INTO testschema.sales_by_month values (20220101, 100);

 *** Failure 2802 Duplicate row error in testschema.sales_by_month.
 Statement# 1, Info =0 
 *** Total elapsed time was 1 second.

Similarly, if we try to update an existing row so that it becomes a duplicate of another row, the update fails:

UPDATE testschema.sales_by_month 
SET sales_dt = 20220101, amount = 100
WHERE sales_dt = 20220104 and amount = 400;

 *** Failure 2802 Duplicate row error in testschema.sales_by_month.
 Statement# 1, Info =0 
 *** Total elapsed time was 1 second.

In other words, simple INSERT-VALUE and UPDATE statements fail if they introduce duplicate rows into a Teradata SET table.

There is a notable exception to this rule. Consider the following staging table, which has the same attributes as the target table:

CREATE MULTISET TABLE testschema.sales_by_month_stg (
  sales_dt DATE
, amount DECIMAL(8,2)
);

The staging table is a MULTISET table and accepts duplicate rows. We populate three rows into the staging table. The first row is a duplicate of a row in the target table. The second and third rows are duplicates of each other, but don’t duplicate any of the target rows.

select * from testschema.sales_by_month_stg;

 *** Query completed. 3 rows found. 2 columns returned. 
 *** Total elapsed time was 1 second.

sales_dt amount
-------- ----------
22/01/01 100.00
22/01/05 500.00
22/01/05 500.00

Now we successfully insert the staging data into the target table (which is a SET table):

INSERT INTO testschema.sales_by_month (sales_dt, amount)
SELECT sales_dt, amount FROM testschema.sales_by_month_stg;

 *** Insert completed. One row added. 
 *** Total elapsed time was 1 second.

If we examine the target table, we can see that a single row for (2022-01-05, 500) has been inserted, and the duplicate row for (2022-01-01, 100) has been discarded. Essentially, Teradata silently discards any duplicate rows when it performs an INSERT-SELECT statement. This includes duplicates that are in the staging table and duplicates that are shared between the staging and target tables.

select * from testschema.sales_by_month order by sales_dt;

 *** Query completed. 6 rows found. 2 columns returned. 
 *** Total elapsed time was 1 second.

sales_dt amount
-------- ----------
22/01/01 100.00
22/01/02 200.00
22/01/03 300.00
22/01/03 200.00
22/01/04 400.00
22/01/05 500.00

Essentially, SET tables behave differently depending on the type of operation being run. An INSERT-VALUE or UPDATE operation suffers a failure if it introduces a duplicate row into the target. An INSERT-SELECT operation doesn’t suffer a failure if the staging table contains a duplicate row, or a duplicate row is shared between the staging and table tables.

In this post, we don’t go into detail on how to convert INSERT-VALUE or UPDATE statements. These statements typically involve one or a few rows and are less impactful in terms of performance than INSERT-SELECT statements. For INSERT-VALUE or UPDATE statements, you can materialize the row (or rows) being created, and join that set to the target table to check for duplicates.

INSERT-SELECT

In the rest of this post, we analyze INSERT-SELECT statements carefully. Customers have told us that INSERT-SELECT operations can comprise up to 78% of the INSERT workload against SET tables. We are concerned with statements with the following form:

INSERT into <target table> SELECT * FROM <staging table>

The schema of the staging table is identical to the target table on a column-by-column basis. As we mentioned earlier, a duplicate row can appear in two different circumstances:

  • The staging table is not set-unique, meaning that there are two or more full row duplicates in the staging data
  • There is a row x in the staging table and an identical row x in the target table

Because Amazon Redshift supports multiset table semantics, it’s possible that the staging table contains duplicates (the first circumstance we listed). Therefore, any automation must address both cases, because either can introduce a duplicate into an Amazon Redshift table.

Based on this analysis, we implemented the following algorithms:

  • MINUS – This implements the full set logic deduplication using SQL MINUS. MINUS works in all cases, including when the staging table isn’t set-unique and when the intersection of the staging table and target table is non-empty. MINUS also has the advantage that NULL values don’t require special comparison logic to overcome NULL to NULL comparisons. MINUS has the following syntax:
    INSERT INTO <target table> (<column list>)
    SELECT <column list> FROM <staging table> 
    MINUS
    SELECT <column list> FROM <target table>;

  • MINUS-MIN-MAX – This is an optimization on MINUS that incorporates a filter to limit the target table scan based on the values in the stage table. The min/max filters allow the query engine to skip large numbers of block during table scans. See Working with sort keys for more details.
    INSERT INTO <target table>(<column list>)
    SELECT <column list> FROM <staging table> 
    MINUS
    SELECT <column list> FROM <target table>
    WHERE <target table>.<sort key> >= (SELECT MIN(<sort key>) FROM <staging table>)
      AND <target table>).<sort key> <= (SELECT MAX(<sort key>) FROM <staging table>)
    );

We also considered other algorithms, but we don’t recommend that you use them. For example, you can perform a GROUP BY to eliminate duplicates in the staging table, but this step is unnecessary if you use the MINUS operator. You can also perform a left (or right) outer join to find shared duplicates between the staging and target tables, but then additional logic is needed to account for NULL = NULL conditions.

Performance

We tested the MINUS and MINUS-MIN-MAX algorithms on Amazon Redshift. We ran the algorithms on two Amazon Redshift clusters. The first configuration consisted of 6 x ra3.4xlarge nodes. The second consisted of 12 x ra3.4xlarge nodes. Each node contained 12 CPU and 96 GB of memory.

We created the stage and target tables with identical sort and distribution keys to minimize data movement. We loaded the same target dataset into both clusters. The target dataset consisted of 1.1 billion rows of data. We then created staging datasets that ranged from 20 million to 200 million rows, in 20 million row increments.

The following graph shows our results.

The test data was artificially generated and some skew was present in the distribution key values. This is manifested in the small deviations from linearity in the performance.

However, you can observe the performance increase that is afforded the MINUS-MIN-MAX algorithm over the basic MINUS algorithm (comparing orange lines or blue lines to themselves). If you’re implementing SET tables in Amazon Redshift, we recommend using MINUS-MIN-MAX because this algorithm provides a happy convergence of simple, readable code and good performance.

Automation

All Amazon Redshift tables allow duplicate rows, i.e., they are MULTISET tables by default. If you are converting a Teradata workload to run on Amazon Redshift, you’ll need to enforce SET semantics outside of the database.

We’re happy to share that AWS SCT will automatically convert your SQL code that operates against SET tables. AWS SCT will rewrite INSERT-SELECT that load SET tables to incorporate the rewrite patterns we described above.

Let’s see how this works. Suppose you have the following target table definition in Teradata:

CREATE SET TABLE testschema.fact (
  id bigint NOT NULL
, se_sporting_event_id INTEGER NOT NULL
, se_sport_type_name VARCHAR(15) NOT NULL
, se_home_team_id INTEGER NOT NULL
, se_away_team_id INTEGER NOT NULL
, se_location_id INTEGER NOT NULL
, se_start_date_time DATE NOT NULL
, se_sold_out INTEGER DEFAULT 0 NOT NULL
, stype_sport_type_name varchar(15) NOT NULL
, stype_short_name varchar(10) NOT NULL
, stype_long_name varchar(60) NOT NULL
, stype_description varchar(120)
, sd_sport_type_name varchar(15) NOT NULL
, sd_sport_league_short_name varchar(10) NOT NULL
, sd_short_name varchar(10) NOT NULL
, sd_long_name varchar(60)
, sd_description varchar(120)
, sht_id INTEGER NOT NULL
, sht_name varchar(30) NOT NULL
, sht_abbreviated_name varchar(10)
, sht_home_field_id INTEGER 
, sht_sport_type_name varchar(15) NOT NULL
, sht_sport_league_short_name varchar(10) NOT NULL
, sht_sport_division_short_name varchar(10)
, sat_id INTEGER NOT NULL
, sat_name varchar(30) NOT NULL
, sat_abbreviated_name varchar(10)
, sat_home_field_id INTEGER 
, sat_sport_type_name varchar(15) NOT NULL
, sat_sport_league_short_name varchar(10) NOT NULL
, sat_sport_division_short_name varchar(10)
, sl_id INTEGER NOT NULL
, sl_name varchar(60) NOT NULL
, sl_city varchar(60) NOT NULL
, sl_seating_capacity INTEGER
, sl_levels INTEGER
, sl_sections INTEGER
, seat_sport_location_id INTEGER
, seat_seat_level INTEGER
, seat_seat_section VARCHAR(15)
, seat_seat_row VARCHAR(10)
, seat_seat VARCHAR(10)
, seat_seat_type VARCHAR(15)
, pb_id INTEGER NOT NULL
, pb_full_name varchar(60) NOT NULL
, pb_last_name varchar(30)
, pb_first_name varchar(30)
, ps_id INTEGER NOT NULL
, ps_full_name varchar(60) NOT NULL
, ps_last_name varchar(30)
, ps_first_name varchar(30)
)
PRIMARY INDEX(id)
;

The stage table is identical to the target table, except that it’s created as a MULTISET table in Teradata.

Next, we create a procedure to load the fact table from the stage table. The procedure contains a single INSERT-SELECT statement:

REPLACE PROCEDURE testschema.insert_select()  
BEGIN
  INSERT INTO testschema.test_fact 
  SELECT * FROM testschema.test_stg;
END;

Now we use AWS SCT to convert the Teradata stored procedure to Amazon Redshift. First, select the stored procedure in the source database tree, then right-click and choose Convert schema.

AWS SCT converts the stored procedure (and embedded INSERT-SELECT) using the MINUS-MIN-MAX rewrite pattern.

And that’s it! Presently, AWS SCT only performs rewrite for INSERT-SELECT because those statements are heavily used by ETL workloads and have the most impact on performance. Although the example we used was embedded in a stored procedure, you can also use AWS SCT to convert the same statements if they’re in BTEQ scripts, macros, or application programs. Download the latest version of AWS SCT and give it a try!

Conclusion

In this post, we showed how to implement SET table semantics in Amazon Redshift. You can use the described design patterns to develop new applications that require SET semantics. Or, if you’re converting an existing Teradata workload, you can use AWS SCT to automatically convert your INSERT-SELECT statements so that they preserve the SET table semantics.

We’ll be back soon with the next installment in this series. Check back for more information on automating your migrations from Teradata to Amazon Redshift. In the meantime, you can learn more about Amazon Redshift and AWS SCT. Happy migrating!


About the Authors

Michael Soo is a Principal Database Engineer with the AWS Database Migration Service team. He builds products and services that help customers migrate their database workloads to the AWS cloud.

Po Hong, PhD, is a Principal Data Architect of the Modern Data Architecture Global Specialty Practice (GSP), AWS Professional Services.  He is passionate about helping customers to adopt innovative solutions and migrate from large scale MPP data warehouses to the AWS modern data architecture.

Migrate your Amazon Redshift cluster to another AWS Region

Post Syndicated from Sindhura Palakodety original https://aws.amazon.com/blogs/big-data/migrate-your-amazon-redshift-cluster-to-another-aws-region/

Amazon Redshift is a fast, fully managed cloud data warehouse that makes it simple and cost-effective to analyze all your data using standard SQL and your existing business intelligence (BI) tools. Amazon Redshift uses SQL to analyze structured and semi-structured data across data warehouses, operational databases, and data lakes, using AWS designed hardware and machine learning (ML) to deliver the best price-performance at any scale.

Customers have reached out to us with a need to migrate their Amazon Redshift clusters from one AWS Region to another. Some of the common reasons include provisioning their clusters geographically closer to their user base to improve latency, for cost-optimization purposes by deploying their clusters in a Region where the pricing is lower, or for migrating clusters to a Region where the rest of their deployments are. This post provides a step-by-step approach to migrate your Amazon Redshift cluster to another Region using the snapshot functionality.

Overview of solution

This solution uses the cross-Region snapshot feature of Amazon Redshift to perform inter-Region migration. The idea is to take multiple manual snapshots of your Amazon Redshift cluster before the cutover deadline to ensure minimal data loss and to migrate the cluster to another Region within the defined maintenance window. You should plan for the maintenance window to be during a period of low or no write activity to minimize downtime. The time taken to copy over the snapshots depends on the size of the snapshot. Before the migration, it’s a good idea to estimate how much time it takes to copy over snapshots to the target Region by testing with similar or larger size datasets in your staging environments. This can help with your planning process.

After you copy the snapshots to the target Region, you can restore the latest snapshot to create a new Amazon Redshift cluster. Snapshots are incremental by nature and track changes to the cluster since the previous snapshot. The copy time is relative to the amount of data that has changed since the last snapshot.

When a snapshot is copied to another Region, it can also act as a standalone, which means that even if only the latest snapshot is copied to the target Region, the restored Amazon Redshift cluster still has all the data. For more information, refer to Amazon Redshift snapshots. Cross-Region snapshot functionality can also be useful for setting up disaster recovery for your Amazon Redshift cluster.

The following diagram illustrates the architecture for cross-Region migration within the same AWS account.

The solution includes the following steps:

  1. Configure cross-Region snapshots of the source Amazon Redshift cluster before the cutover deadline.
  2. Restore the latest snapshots to create a new Amazon Redshift cluster in the target Region.
  3. Point your applications to the new Amazon Redshift cluster.

For encrypted snapshots, there is an additional step of creating a new encryption key and performing a snapshot grant before you can copy the snapshot to the target Region.

Prerequisites

For the migration process, select a maintenance window during when there is low write activity, and be aware of the RTO and RPO requirements of the organization.

The following steps walk you through setting up an Amazon Redshift cluster in the source Region and populating it with a sample dataset. For this post, we use US West (Oregon) as the source Region and US East (N. Virginia) as the target Region. If you already have a source Amazon Redshift cluster, you can skip these prerequisite steps.

Create an Amazon Redshift cluster in the source Region

To create your cluster in the source Region, complete the following steps:

  1. Open the Amazon Redshift console in your source Region.
  2. Choose Clusters in the navigation pane and choose Clusters again on the menu.
  3. Choose Create cluster.
  4. For Cluster identifier, enter redshift-cluster-source.
  5. Select Production for cluster use.

This option allows you to select specific instance types and load the sample data of your choice. Note that you are charged for Amazon Redshift instances and storage for the entire time until you delete the cluster. For more information about pricing, see Amazon Redshift pricing.

  1. For Node type, choose your preferred node type.
  2. For Number of nodes, enter the number of nodes to use.

For this post, we use four dc2.large instances.

  1. Under Database configurations, enter a user name and password for the cluster.

As a best practice, change the default user name to a custom user name (for this post, mydataadmin) and follow the password guidelines.

To load the sample data from an external Amazon Simple Storage Service (Amazon S3) bucket to the source cluster, you need to create an AWS Identity and Access Management (IAM) role.

  1. Under Cluster permissions, on the Manage IAM roles drop-down menu, choose Create IAM role.
  2. Select Any S3 bucket and choose Create IAM role as default.
  3. For Additional configurations, turn Use defaults off.
  4. In the Network and security section, choose a VPC and cluster subnet group.

For more information about creating a cluster, refer to Creating a cluster in a VPC.

  1. Expand Database configurations.

We recommend using custom values instead of the defaults.

  1. For Database name, enter stagingdb.
  2. For Database port, enter 7839.
  3. For Encryption, select Disabled.

We enable encryption in a later step.

  1. Leave the other options as default and choose Create cluster.
  2. When the cluster is available, enable audit logging on the cluster.

Audit logging records information about connections and user activities in your database. This is useful for security as well as troubleshooting purposes.

To meet security best practices, you also create a new Amazon Redshift parameter group.

  1. Choose Configurations and Workload management to create your parameter group.
  2. Make sure that the parameters require_ssl and enable_user_activity_logging are set to true.
  3. On the Properties tab, choose the Edit menu in the Database configurations section and choose Edit parameter group.
  4. Associate the newly created parameter group to the Amazon Redshift cluster.

If this change prompts you to reboot, choose Reboot.

Load the sample dataset in the source Amazon Redshift cluster

When the cluster is ready, it’s time to load the sample dataset from the S3 bucket s3://redshift-immersionday-labs/data/. The following tables are part of the dataset:

  • REGION (5 rows)
  • NATION (25 rows)
  • CUSTOMER (15 million rows)
  • ORDERS (76 million rows)
  • PART (20 million rows)
  • SUPPLIER (1 million rows)
  • LINEITEM (600 million rows)
  • PARTSUPPLIER (80 million rows)

It’s a best practice for the Amazon Redshift cluster to access the S3 bucket via VPC gateway endpoints in order to enhance data loading performance, because the traffic flows through the AWS network, avoiding the internet.

Before we can load our data into Amazon S3, we need to enable a VPC endpoint via Amazon Virtual Private Cloud (Amazon VPC).

  1. On the Amazon VPC console, choose Endpoints.
  2. Choose Create endpoint.
  3. For Name tag, enter redshift-s3-vpc-endpoint.
  4. For Service category, select AWS services.
  5. Search for S3 and select the Gateway type endpoint.
  6. Choose the same VPC where your cluster is provisioned and select the route table.
  7. Leave everything else as default and choose Create endpoint.

Wait for the Gateway endpoint status to change to Available.

Next, you enable enhanced VPC routing.

  1. Open the Amazon Redshift console in the source Region.
  2. Choose your source cluster.
  3. On the Properties tab, in the Network and security settings section, choose Edit.
  4. For Enhanced VPC routing, select Enabled.
  5. Choose Save changes.

Wait for the cluster status to change to Available.

You need to create tables in order to load the sample data into the cluster. We recommend using the Amazon Redshift web-based query editor.

  1. On the Amazon Redshift console, choose Editor in the navigation pane and choose Query editor.

You can also use the new query editor V2.

  1. Choose Connect to database.
  2. Select Create new connection.
  3. Enter the database name and user name.
  4. Choose Connect.

For this post, we use the TPC data example from the Amazon Redshift Immersion Labs.

  1. Navigate to the Data Loading section of the Immersion Day Labs.
  2. Follow the instructions in the Create Tables section to create the tables in your source cluster.
  3. After you create the tables, follow the instructions in Loading Data section to load the data into the cluster.

Loading the data took approximately 17 minutes in the US West (Oregon) Region. This may vary depending on the Region and network bandwidth at that point in time.

After the data is loaded successfully into the source cluster, you can query it to make sure that you see the data in all the tables.

  1. Choose a table (right-click) and choose Preview data.
  2. Drop the customer table using the query DROP TABLE customer;.

We add the table back later to demonstrate incremental changes.

You can check the storage size to verify the size of the data loaded.

  1. Choose Clusters in the navigation pane.
  2. Choose your source cluster.
  3. Verify the storage size in the General information section, under Storage used.

Your source Amazon Redshift cluster is now loaded with a sample dataset and is ready to use.

Configure cross-Region snapshots in the source Region

To perform inter-Region migration, the first step is to configure cross-Region snapshots. The cross-Region snapshot feature enables you to copy over snapshots automatically to another Region.

  1. Open the Amazon Redshift console in the source Region.
  2. Select your Amazon Redshift cluster.
  3. On the Actions menu, choose Configure cross-region snapshot.
  4. For Copy snapshots, select Yes.
  5. For Destination Region, choose your target Region (for this post, us-east-1).
  6. Configure the manual snapshot retention period according to your requirements.
  7. Choose Save.

After the cross-Region snapshot feature is configured, any subsequent automated or manual snapshots are automatically copied to the target Region.

  1. To create a manual snapshot, choose Clusters in the navigation pane and choose Snapshots.
  2. Choose Create snapshot.
  3. For Cluster identifier, choose redshift-cluster-source.
  4. Adjust the snapshot retention period based on your requirements.
  5. Choose Create snapshot.

The idea is to take multiple snapshots until the cutover deadline so as to capture as much data as possible for minimal data loss based on your RTO and RPO requirements. The first snapshot creation took about 4 minutes for 28.9 GB of data, but subsequent snapshots are incremental in nature.

This snapshot gets automatically copied to the target Region from the source Region. You can open the Amazon Redshift console in the target Region to verify the copy.

As shown in the following screenshot, the snapshot of size 28.9 GB took around 44 minutes to get copied to the target Region because it’s the first snapshot containing all the data in the cluster. Depending on the Regions involved and the amount of data to copy, a cross-Region snapshot copy may take hours to complete.

Let’s now simulate incremental changes being made to the source cluster.

  1. Open the Amazon Redshift console in the source Region and open the query editor.
  2. Create a new table called customer in the cluster using the following query:
    create table customer (
      C_CUSTKEY bigint NOT NULL,
      C_NAME varchar(25),
      C_ADDRESS varchar(40),
      C_NATIONKEY bigint,
      C_PHONE varchar(15),
      C_ACCTBAL decimal(18,4),
      C_MKTSEGMENT varchar(10),
      C_COMMENT varchar(117))
    diststyle all;

  3. Load data into the customer table using the following command:
    copy customer from 's3://redshift-immersionday-labs/data/customer/customer.tbl.'
    iam_role default
    region 'us-west-2' lzop delimiter '|' COMPUPDATE PRESET;

  4. To create a manual snapshot containing incremental data, choose Clusters in the navigation pane, then choose Snapshots.
  5. Provide the necessary information and choose Create snapshot.

Because the cross-Region snapshot functionality is enabled, this incremental snapshot is automatically copied to the target Region. In the following example, the snapshot took approximately 11 minutes to copy to the target Region from the source Region. This time varies from Region to Region and is based on the amount of data being copied.

Restore snapshots to same or higher instance types in the target Region

When the latest snapshot is successfully copied to the target Region, you can restore the snapshot.

  1. Open the Amazon Redshift console in the target Region.
  2. On the Snapshots page, select your snapshot.
  3. On the Restore from snapshot menu, choose Restore to a provisioned cluster.
  4. For Cluster identifier, enter redshift-cluster-target.
  5. For Node type¸ you can use the same instance type or upgrade to a higher instance type.
  6. For Number of nodes, choose the number of nodes you need.

If you choose to upgrade your instance to RA3, refer to Upgrading to RA3 node types to determine the number of nodes you need.

For this post, we still use four nodes of the dc2.large instance type.

  1. Under Database configurations, for Database name¸ enter stagingdb.
  2. Leave the rest of the settings as default (or modify them per your requirements) and choose Restore cluster from snapshot.

A new Amazon Redshift cluster gets provisioned from the snapshot in the target Region.

Follow the same security best practices that you applied to the source cluster for the target cluster.

Point your applications to the new Amazon Redshift cluster

When the target cluster is available, configure your applications to connect to the new target Amazon Redshift endpoints. New clusters have a different Domain Name System (DNS) endpoint. This means that you must update all clients to refer to the new endpoint.

Inter-Region migration steps for encrypted data

If the data in your Amazon Redshift cluster is encrypted, you need to perform additional steps in your inter-Region migration. If data encryption is already enabled, you can skip to the steps for snapshot copy grant.

Enable data encryption in the source Amazon Redshift cluster

To enable data encryption in the source cluster, we use Amazon Key Management Service (AWS KMS).

  1. Open the AWS KMS console in the source Region.
  2. Create a KMS key called redshift-source-key.
  3. Enable key rotation.
  4. On the Amazon Redshift console (still in the source Region), select your cluster.
  5. If a cross-Region snapshot is enabled, choose Configure cross-region snapshot on the Actions menu.
  6. Select No and choose Save.
  7. On the Properties tab, in the Database configurations section, choose the Edit menu and choose Edit encryption.
  8. Select Use AWS Key Management Service (AWS KMS).
  9. Select Use key from current account and choose the key you created.
  10. Choose Save changes.

The time taken to encrypt the data is based on the amount of data present in the cluster.

If the data is encrypted, any subsequent snapshots are also automatically encrypted.

Snapshot copy grant

When you copy the encrypted snapshots to the target Region, the existing KMS key in the source Region doesn’t work in the target Region because KMS keys are specific to the Region where they’re created. You need to create another KMS key in the target Region and grant it access.

  1. Open the AWS KMS console in the target Region.
  2. If you don’t already have a KMS key to use, create a key called redshift-target-key.
  3. Enable key rotation.
  4. Open the Amazon Redshift console in the source Region.
  5. Select the cluster and on the Actions menu, choose Configure cross-region snapshot.
  6. For Copy snapshots, select Yes.
  7. For Choose a snapshot copy grant, choose Create new grant.
  8. For Snapshot copy grant name, enter redshift-target-grant.
  9. For KMS key ID, choose the key that you created for the grant.

If you don’t specify a key ID, the grant applies to your default key.

  1. Choose Save.

Any subsequent snapshots copied to the target Region are now encrypted with the key created in the target Region.

  1. After the snapshot is copied to the target Region, restore the cluster from the encrypted snapshot, following the steps from earlier in this post.

For more details on the encryption process, refer to Copying AWS KMS–encrypted snapshots to another AWS Region.

After you restore from the encrypted snapshot, the restored cluster is automatically encrypted with the key you created in the target Region.

Make sure that your applications point to the new cluster endpoint when the cluster is available.

Clean up

If you created any Amazon Redshift clusters or snapshots for testing purposes, you can delete these resources to avoid incurring any future charges.

For instructions on deleting the snapshots, refer to Deleting manual snapshots.

For instructions on deleting the Amazon Redshift cluster, refer to Deleting a cluster.

Conclusion

This post showed how to migrate your Amazon Redshift cluster to another Region using the cross-Region snapshot functionality. Amazon Redshift migration requires some prior planning depending on the Regions involved and the amount of data to copy over. Snapshot creation and copying may take a significant amount of time. The first snapshot contains all the data in the cluster and therefore it may take longer, but subsequent snapshots contain incremental changes and may take less time depending on the changes made. It’s a good idea to estimate how much time the snapshot copy takes by performing some tests in your staging environments with snapshots of a similar size or slightly larger than the ones in the production environment so you can plan for minimal data loss and meet RTO and RPO requirements.

For further details about the Amazon Redshift snapshot functionality, refer to Working with Snapshots.


About the Author

Sindhura Palakodety is a Solutions Architect at Amazon Web Services. She is passionate about helping customers build enterprise-scale Well-Architected solutions on the AWS platform and specializes in Containers and Data Analytics domains.

Make data available for analysis in seconds with Upsolver low-code data pipelines, Amazon Redshift Streaming Ingestion, and Amazon Redshift Serverless

Post Syndicated from Roy Hasson original https://aws.amazon.com/blogs/big-data/make-data-available-for-analysis-in-seconds-with-upsolver-low-code-data-pipelines-amazon-redshift-streaming-ingestion-and-amazon-redshift-serverless/

Amazon Redshift is the most widely used cloud data warehouse. Amazon Redshift makes it easy and cost-effective to perform analytics on vast amounts of data. Amazon Redshift launched Streaming Ingestion for Amazon Kinesis Data Streams, which enables you to load data into Amazon Redshift with low latency and without having to stage the data in Amazon Simple Storage Service (Amazon S3). This new capability enables you to build reports and dashboards and perform analytics using fresh and current data, without needing to manage custom code that periodically loads new data.

Upsolver is an AWS Advanced Technology Partner that enables you to ingest data from a wide range of sources, transform it, and load the results into your target of choice, such as Kinesis Data Streams and Amazon Redshift. Data analysts, engineers, and data scientists define their transformation logic using SQL, and Upsolver automates the deployment, scheduling, and maintenance of the data pipeline. It’s pipeline ops simplified!

There are multiple ways to stream data to Amazon Redshift and in this post we will cover two options that Upsolver can help you with: First, we show you how to configure Upsolver to stream events to Kinesis Data Streams that are consumed by Amazon Redshift using Streaming Ingestion. Second, we demonstrate how to write event data to your data lake and consume it using Amazon Redshift Serverless so you can go from raw events to analytics-ready datasets in minutes.

Prerequisites

Before you get started, you need to install Upsolver. You can sign up for Upsolver and deploy it directly into your VPC to securely access Kinesis Data Streams and Amazon Redshift.

Configure Upsolver to stream events to Kinesis Data Streams

The following diagram represents the architecture to write events to Kinesis Data Streams and Amazon Redshift.

To implement this solution, you complete the following high-level steps:

  1. Configure the source Kinesis data stream.
  2. Execute the data pipeline.
  3. Create an Amazon Redshift external schema and materialized view.

Configure the source Kinesis data stream

For the purpose of this post, you create an Amazon S3 data source that contains sample retail data in JSON format. Upsolver ingests this data as a stream; as new objects arrive, they’re automatically ingested and streamed to the destination.

  1. On the Upsolver console, choose Data Sources in the navigation sidebar.
  2. Choose New.
  3. Choose Amazon S3 as your data source.
  4. For Bucket, you can use the bucket with the public dataset or a bucket with your own data.
  5. Choose Continue to create the data source.
  6. Create a data stream in Kinesis Data Streams, as shown in the following screenshot.

This is the output stream Upsolver uses to write events that are consumed by Amazon Redshift.

Next, you create a Kinesis connection in Upsolver. Creating a connection enables you to define the authentication method Upsolver uses—for example, an AWS Identity and Access Management (IAM) access key and secret key or an IAM role.

  1. On the Upsolver console, choose More in the navigation sidebar.
  2. Choose Connections.
  3. Choose New Connection.
  4. Choose Amazon Kinesis.
  5. For Region, enter your AWS Region.
  6. For Name, enter a name for your connection (for this post, we name it upsolver_redshift).
  7. Choose Create.

Before you can consume the events in Amazon Redshift, you must write them to the output Kinesis data stream.

  1. On the Upsolver console, navigate to Outputs and choose Kinesis.
  2. For Data Sources, choose the Kinesis data source you created in the previous step.
  3. Depending on the structure of your event data, you have two choices:
    1. If the event data you’re writing to the output doesn’t contain any nested fields, select Tabular. Upsolver automatically flattens nested data for you.
    2. To write your data in a nested format, select Hierarchical.
  4. Because we’re working with Kinesis Data Streams, select Hierarchical.

Execute the data pipeline

Now that the stream is connected from the source to an output, you must select which fields of the source event you wish to pass through. You can also choose to apply transformations to your data—for example, adding correct timestamps, masking sensitive values, and adding computed fields. For more information, refer to Quick guide: SQL data transformation.

After adding the columns you want to include in the output and applying transformations, choose Run to start the data pipeline. As new events arrive in the source, Upsolver automatically transforms them and forwards the results to the output stream. There is no need to schedule or orchestrate the pipeline; it’s always on.

Create an Amazon Redshift external schema and materialized view

First, create an IAM role with the appropriate permissions (for more information, refer to Streaming ingestion). Now you can use the Amazon Redshift query editor, AWS Command Line Interface (AWS CLI), or API to run the following SQL statements.

  1. Create an external schema that is backed by Kinesis Data Streams. The following command requires you to include the IAM role you created earlier:
    CREATE EXTERNAL SCHEMA upsolver
    FROM KINESIS
    IAM_ROLE 'arn:aws:iam::123456789012:role/redshiftadmin';

  2. Create a materialized view that allows you to run a SELECT statement against the event data that Upsolver produces:
    CREATE MATERIALIZED VIEW mv_orders AS
    SELECT ApproximateArrivalTimestamp, SequenceNumber,
       json_extract_path_text(from_varbyte(Data, 'utf-8'), 'orderId') as order_id,
       json_extract_path_text(from_varbyte(Data, 'utf-8'), 'shipmentStatus') as shipping_status
    FROM upsolver.upsolver_redshift;

  3. Instruct Amazon Redshift to materialize the results to a table called mv_orders:
    REFRESH MATERIALIZED VIEW mv_orders;

  4. You can now run queries against your streaming data, such as the following:
    SELECT * FROM mv_orders;

Use Upsolver to write data to a data lake and query it with Amazon Redshift Serverless

The following diagram represents the architecture to write events to your data lake and query the data with Amazon Redshift.

To implement this solution, you complete the following high-level steps:

  1. Configure the source Kinesis data stream.
  2. Connect to the AWS Glue Data Catalog and update the metadata.
  3. Query the data lake.

Configure the source Kinesis data stream

We already completed this step earlier in the post, so you don’t need to do anything different.

Connect to the AWS Glue Data Catalog and update the metadata

To update the metadata, complete the following steps:

  1. On the Upsolver console, choose More in the navigation sidebar.
  2. Choose Connections.
  3. Choose the AWS Glue Data Catalog connection.
  4. For Region, enter your Region.
  5. For Name, enter a name (for this post, we call it redshift serverless).
  6. Choose Create.
  7. Create a Redshift Spectrum output, following the same steps from earlier in this post.
  8. Select Tabular as we’re writing output in table-formatted data to Amazon Redshift.
  9. Map the data source fields to the Redshift Spectrum output.
  10. Choose Run.
  11. On the Amazon Redshift console, create an Amazon Redshift Serverless endpoint.
  12. Make sure you associate your Upsolver role to Amazon Redshift Serverless.
  13. When the endpoint launches, open the new Amazon Redshift query editor to create an external schema that points to the AWS Glue Data Catalog (see the following screenshot).

This enables you to run queries against data stored in your data lake.

Query the data lake

Now that your Upsolver data is being automatically written and maintained in your data lake, you can query it using your preferred tool and the Amazon Redshift query editor, as shown in the following screenshot.

Conclusion

In this post, you learned how to use Upsolver to stream event data into Amazon Redshift using streaming ingestion for Kinesis Data Streams. You also learned how you can use Upsolver to write the stream to your data lake and query it using Amazon Redshift Serverless.

Upsolver makes it easy to build data pipelines using SQL and automates the complexity of pipeline management, scaling, and maintenance. Upsolver and Amazon Redshift enable you to quickly and easily analyze data in real time.

If you have any questions, or wish to discuss this integration or explore other use cases, start the conversation in our Upsolver Community Slack channel.


About the Authors

Roy Hasson is the Head of Product at Upsolver. He works with customers globally to simplify how they build, manage and deploy data pipelines to deliver high quality data as a product. Previously, Roy was a Product Manager for AWS Glue and AWS Lake Formation.

Mei Long is a Product Manager at Upsolver. She is on a mission to make data accessible, usable and manageable in the cloud. Previously, Mei played an instrumental role working with the teams that contributed to the Apache Hadoop, Spark, Zeppelin, Kafka, and Kubernetes projects.

Maneesh Sharma is a Senior Database Engineer  at AWS with more than a decade of experience designing and implementing large-scale data warehouse and analytics solutions. He collaborates with various Amazon Redshift Partners and customers to drive better integration.

Build and deploy custom connectors for Amazon Redshift with Amazon Lookout for Metrics

Post Syndicated from Chris King original https://aws.amazon.com/blogs/big-data/build-and-deploy-custom-connectors-for-amazon-redshift-with-amazon-lookout-for-metrics/

Amazon Lookout for Metrics detects outliers in your time series data, determines their root causes, and enables you to quickly take action. Built from the same technology used by Amazon.com, Lookout for Metrics reflects 20 years of expertise in outlier detection and machine learning (ML). Read our GitHub repo to learn more about how to think about your data when setting up an anomaly detector.

In this post, we discuss how to build and deploy custom connectors for Amazon Redshift using Lookout for Metrics.

Introduction to time series data

You can use time series data to measure and monitor any values that shift from one point in time to another. A simple example is stock prices over a given time interval or the number of customers seen per day in a garage. You can use these values to spot trends and patterns and make better decisions about likely future events. Lookout for Metrics enables you to structure important data into a tabular format (like a spreadsheet or database table), to provide historical values to learn from, and to provide continuous values of data.

Connect your data to Lookout for Metrics

Since launch, Lookout for Metrics has supported providing data from the following AWS services:

It also supports external data sources such as Salesforce, Marketo, Dynatrace, ServiceNow, Google Analytics, and Amplitude, all via Amazon AppFlow.

These connectors all support continuous delivery of new data to Lookout for Metrics to learn to build a model for anomaly detection.

Native connectors are an effective option to get started quickly with CloudWatch, Amazon S3, and via Amazon AppFlow for the external services. Additionally, these work great for your relational database management system (RDBMS) data if you have stored your information in a singular table, or you can create a procedure to populate and maintain that table going forward.

When to use a custom connector

In cases where you want more flexibility, you can use Lookout for Metrics custom connectors. If your data is in a state that requires an extract, transform, and load (ETL) process, such as joining from multiple tables, transforming a series of values into a composite, or performing any complex postprocessing before delivering the data to Lookout for Metrics, you can use custom connectors. Additionally, if you’re starting with data in an RDBMS and you wish to provide a historical sample for Lookout for Metrics to learn from first, you should use a custom connector. This allows you to feed in a large volume of history first, bypassing the coldstart requirements and achieving a higher quality model sooner.

For this post, we use Amazon Redshift as our RDBMS, but you can modify this approach for other systems.

You should use custom connectors in the following situations:

  • Your data is spread over multiple tables
  • You need to perform more complex transformations or calculations before it fits to a detector’s configuration
  • You want to use all your historical data to train your detector

For a quicker start, you can use built-in connectors in the following situations:

  • Your data exists in a singular table that only contains information used by your anomaly detector
  • You’re comfortable using your historical data and then waiting for the coldstart period to elapse before beginning anomaly detection

Solution overview

All content discussed in this post is hosted on the GitHub repo.

For this post, we assume that you’re storing your data in Amazon Redshift over a few tables and that you wish to connect it Lookout for Metrics for anomaly detection.

The following diagram illustrates our solution architecture.

Solution Architecture

At a high level, we start with an AWS CloudFormation template that deploys the following components:

  • An Amazon SageMaker notebook instance that deploys the custom connector solution.
  • An AWS Step Functions workflow. The first step performs a historical crawl of your data; the second configures your detector (the trained model and endpoint for Lookout for Metrics).
  • An S3 bucket to house all your AWS Lambda functions as deployed (omitted from the architecture diagram).
  • An S3 bucket to house all your historical and continuous data.
  • A CloudFormation template and Lambda function that starts crawling your data on a schedule.

To modify this solution to fit your own environment, update the following:

  • A JSON configuration template that describes how your data should look to Lookout for Metrics and the name of your AWS Secrets Manager location used to retrieve authentication credentials.
  • A SQL query that retrieves your historical data.
  • A SQL query that retrieves your continuous data.

After you modify those components, you can deploy the template and be up and running within an hour.

Deploy the solution

To make this solution explorable from end to end, we have included a CloudFormation template that deploys a production-like Amazon Redshift cluster. It’s loaded with sample data for testing with Lookout for Metrics. This is a sample ecommerce dataset that projects roughly 2 years into the future from the publication of this post.

Create your Amazon Redshift cluster

Deploy the provided template to create the following resources in your account:

  • An Amazon Redshift cluster inside a VPC
  • Secrets Manager for authentication
  • A SageMaker notebook instance that runs all the setup processes for the Amazon Redshift database and initial dataset loading
  • An S3 bucket that is used to load data into Amazon Redshift

The following diagram illustrates how these components work together.

Production Redshift Setup

We provide Secrets Manager with credential information for your database, which is passed to a SageMaker notebook’s lifecycle policy that runs on boot. Once booted, the automation creates tables inside your Amazon Redshift cluster and loads data from Amazon S3 into the cluster for use with our custom connector.

To deploy these resources, complete the following steps:

  1. Choose Launch Stack:
  2. Choose Next.
    Setup step described by text
  3. Leave the stack details at their default and choose Next again.Setup step described by text
  4. Leave the stack options at their default and choose Next again.Setup step described by text
  1. Select I acknowledge that AWS CloudFormation might create IAM resources, then Choose Create stack.Setup step described by text

The job takes a few minutes to complete. You can monitor its progress on the AWS CloudFormation console.

CloudFormation Status

When the status changes to CREATE_COMPLETE, you’re ready to deploy the rest of the solution.

Stack Complete

Data structure

We have taken our standard ecommerce dataset and split it into three specific tables so that we can join them later via the custom connector. In all probability, your data is spread over various tables and needs to be normalized in a similar manner.

The first table indicates the user’s platform, (what kind of device users are using, such as phone or web browser).

ID Name
1 pc_web

The next table indicates our marketplace (where the users are located).

ID Name
1 JP

Our ecommerce table shows the total values for views and revenue at this time.

ID TS Platform Marketplace Views Revenue
1 01/10/2022 10:00:00 1 1 90 2458.90

When we run queries later in this post, they’re against a database with this structure.

Deploy a custom connector

After you deploy the previous template, complete the following steps to deploy a custom connector:

  1. On the AWS CloudFormation console, navigate to the Outputs tab of the template you deployed earlier.
    Outputs Link
  2. Note the value of RedshiftCluster and RedshiftSecret, then save them in a temporary file to use later.
    Output Values
  3. Choose Launch stack to deploy your resources with AWS CloudFormation:
  4. Choose Next.
    CloudFormation Setup
  5. Update the value for the RedshiftCluster and RedshiftSecret with the information you copied earlier.
  6. Choose Next.CloudFormation Setup
  7. Leave the stack options at their default and choose Next.Cloudformation Setup
  8. Select I acknowledge that AWS CloudFormation might create IAM resources, then choose Create stack.Cloudformation Setup

The process takes 30–40 minutes to complete, after which you have a fully deployed solution with the demo environment.

View your anomaly detector

After you deploy the solution, you can locate your detector and review any found anomalies.

  1. Sign in to the Lookout for Metrics console in us-east-1.
  2. In the navigation pane, choose Detectors.Lookout for Metrics Detectors Link

The Detectors page lists all your active detectors.

  1. Choose the detector l4m-custom-redshift-connector-detector.

Now you can view your detector’s configuration, configure alerts, and review anomalies.

To view anomalies, either choose Anomalies in the navigation page or choose View anomalies on the detector page.
View Anomalies Link

After a period of time, usually no more than a few days, you should see a list of anomalies on this page. You can explore them in depth to view how the data provided seemed anomalous. If you provided your own dataset, the anomalies may only show up after an unusual event.

Anomalies List

Now that you have the solution deployed and running, let’s discuss how this connector works in depth.

How a custom connector works

In this section, we discuss the connector’s core components. We also demonstrate how to build a custom connector, authenticate to Amazon Redshift, modify queries, and modify the detector and dataset.

Core components

You can run the following components and modify them to support your data needs:

When you deploy ai_ops/l4m-redshift-solution.yaml, it creates the following:

  • An S3 bucket for storing all Lambda functions.
  • A role for a SageMaker notebook that has access to modify all relevant resources.
  • A SageMaker notebook lifecycle config that contains the startup script to clone all automation onto the notebook and manage the params.json file. And runs the shell script (ai_ops/deploy_custom_connector.sh) to deploy the AWS SAM applications and further update the params.json file.

ai_ops/deploy_custom_connector.sh starts by deploying ai_ops/template.yaml, which creates the following:

  • An S3 bucket for storing the params.json file and all input data for Lookout for Metrics.
  • An S3 bucket policy to allow Lookout for Metrics to communicate with Amazon S3.
  • A Lambda function that is invoked on the bucket when the params.json file is uploaded and starts the Step Functions state machine.
  • An AWS Identity and Access Management (IAM) role to run the state machine.
  • A shared Lambda layer of support functions.
  • A role for Lookout for Metrics to access data in Amazon S3.
  • A Lambda function to crawl all historical data.
  • A Lambda function to create and activate a Lookout for Metrics detector.
  • A state machine that manages the flow between creating that historical dataset and the detector.

After ai_ops/deploy_custom_connector.sh creates the first batch of items, it updates the params.json file with new relevant information from the detector and the IAM roles. It also modifies the Amazon Redshift cluster to allow the new role for Lookout for Metrics to communicate with the cluster. After sleeping for 30 seconds to facilitate IAM propagation, the script copies the params.json file to the S3 bucket, which invokes the state machine deployed already.

Then the script deploys another AWS SAM application defined in l4m-redshift-continuous-crawl.yaml. This simple application defines and deploys an event trigger to initiate the crawling of live data on a schedule (hourly for example) and a Lambda function that performs the crawl.

Both the historical crawled data and the continuously crawled data arrives in the same S3 bucket. Lookout for Metrics uses the information first for training, then as inference data, where it’s checked for anomalies as it arrives.

Each Lambda function also contains a query.sql file that provides the base query that is handed to Amazon Redshift. Later the functions append UNLOAD to each query and deliver the data to Amazon S3 via CSV.

Build a custom connector

Start by forking this repository into your own account or downloading a copy for private development. When making substantial changes, make sure that the references to this particular repository in the following files are updated and point to publicly accessible endpoints for Git:

  • README.md – This file, in particular the Launch stack buttons, assumes you’re using the live version you see in this repository only
  • ai_ops/l4m-redshift-solution.yaml – In this template, a Jupyter notebook lifecycle configuration defines the repository to clone (deploys the custom connector)
  • sample_resources/redshift/l4m-redshift-sagemakernotebook.yaml – In this template, a Amazon SageMaker Notebook lifecycle configuration defines the repository to clone (deploys the production Amazon Redshift example).

Authenticate to Amazon Redshift

When exploring how to extend this into your own environment, the first thing to consider is the authentication to your Amazon Redshift cluster. You can accomplish this by using the Amazon Redshift Data API and by storing the credentials inside AWS Secrets Manager.

In Secrets Manager, this solution looks for the known secret name redshift-l4mintegration and contains a JSON structure like the following:

{
  "password": "DB_PASSWORD",
  "username": "DB_USERNAME",
  "dbClusterIdentifier": "REDSHIFT_CLUSTER_ID",
  "db": "DB_NAME",
  "host": "REDSHIFT_HOST",
  "port": 8192
}

If you want to use a different secret name than the one provided, you need to update the value in ai_ops/l4m-redshift-solution.yaml. If you want to change the other parameters’ names, you need to search for them in the repository and update their references accordingly.

Modify queries to Amazon Redshift

This solution uses the Amazon Redshift Data API to allow for queries that can be run asynchronously from the client calling for them.

Specifically, it allows a Lambda function to start a query with the database and then let the DB engine manage everything, including the writing of the data in a desired format to Amazon S3. Because we let the DB engine handle this, we simplify the operations of our Lambda functions and don’t have to worry about runtime limits. If you want to perform more complex transformations, you may want to build out more Step Functions-based AWS SAM applications to handle that work, perhaps even using Docker containers over Lambda.

For most modifications, you can edit the query files stored in the two Lambda functions provided:

Pay attention to the continuous crawl to make sure that the date ranges coincide with your desired detection interval. For example:

select ecommerce.ts as timestamp, ecommerce.views, ecommerce.revenue, platform.name as platform, marketplace.name as marketplace
from ecommerce, platform, marketplace
where ecommerce.platform = platform.id
	and ecommerce.marketplace = marketplace.id
    and ecommerce.ts < DATEADD(hour, 0, getdate())
    and ecommerce.ts > DATEADD(hour, -1, getdate())

The preceding code snippet is our demo continuous crawl function and uses the DATEADD function to compute data within the last hour. Coupled with the CloudWatch Events trigger that schedules this function for hourly, it allows us to stream data to Lookout for Metrics reliably.

The work defined in the query.sql files is only a portion of the final computed query. The full query is built by the respective Python files in each folder and appends the following:

  • IAM role for Amazon Redshift to use for the query
  • S3 bucket information for where to place the files
  • CSV file export defined

It looks like the following code:

unload ('select ecommerce.ts as timestamp, ecommerce.views, ecommerce.revenue, platform.name as platform, marketplace.name as marketplace
from ecommerce, platform, marketplace
where ecommerce.platform = platform.id
	and ecommerce.marketplace = marketplace.id
    and ecommerce.ts < DATEADD(hour, 0, getdate())
    and ecommerce.ts > DATEADD(hour, -1, getdate())') 
to 's3://BUCKET/ecommerce/live/20220112/1800/' 
iam_role 'arn:aws:iam::ACCOUNT_ID:role/custom-rs-connector-LookoutForMetricsRole-' header CSV;

As long as your prepared query can be encapsulated by the UNLOAD statement, it should work with no issues.

If you need to change the frequency for how often the continuous detector function runs, update the cron expression in ai_ops/l4m-redshift-continuous-crawl.yaml. It’s defined in the last line as Schedule: cron(0 * * * ? *).

Modify the Lookout for Metrics detector and dataset

The final components focus on Lookout for Metrics itself, mainly the detector and dataset configurations. They’re both defined in ai_ops/params.json.

The included file looks like the following code:

{
  "database_type": "redshift",  
  "detector_name": "l4m-custom-redshift-connector-detector",
    "detector_description": "A quick sample config of how to use L4M.",
    "detector_frequency": "PT1H",
    "timestamp_column": {
        "ColumnFormat": "yyyy-MM-dd HH:mm:ss",
        "ColumnName": "timestamp"
    },
    "dimension_list": [
        "platform",
        "marketplace"
    ],
    "metrics_set": [
        {
            "AggregationFunction": "SUM",
            "MetricName": "views"
        },
        {
            "AggregationFunction": "SUM",
            "MetricName": "revenue"
        }
    ],
    "metric_source": {
        "S3SourceConfig": {
            "FileFormatDescriptor": {
                "CsvFormatDescriptor": {
                    "Charset": "UTF-8",
                    "ContainsHeader": true,
                    "Delimiter": ",",
                    "FileCompression": "NONE",
                    "QuoteSymbol": "\""
                }
            },
            "HistoricalDataPathList": [
                "s3://id-ml-ops2-inputbucket-18vaudty8qtec/ecommerce/backtest/"
            ],
            "RoleArn": "arn:aws:iam::ACCOUNT_ID:role/id-ml-ops2-LookoutForMetricsRole-IZ5PL6M7YKR1",
            "TemplatedPathList": [
                    ""
                ]
        }
    },
    "s3_bucket": "",
    "alert_name": "alerter",
    "alert_threshold": 1,
    "alert_description": "Exports anomalies into s3 for visualization",
    "alert_lambda_arn": "",
    "offset": 300,
    "secret_name": "redshift-l4mintegration"
}

ai_ops/params.json manages the following parameters:

  • database_type
  • detector_name
  • detector_description
  • detector_frequency
  • timestamp_column and details
  • dimension_list
  • metrics_set
  • offset

Not every value can be defined statically ahead of time; these are updated by ai_ops/params_builder.py:

  • HistoricalDataPathList
  • RoleArn
  • TemplatedPathList
  • s3_bucket

To modify any of these entities, update the file responsible for them and your detector is modified accordingly.

Clean up

Follow the steps in this section to clean up all resources created by this solution and make sure you’re not billed after evaluating or using the solution.

  1. Empty all data from the S3 buckets that were created from their respective templates:
    1. ProductionRedshiftDemo – S3ContentBucket
    2. CustomRedshiftConnector – S3LambdaBucket
    3. custom-rs-connector – InputBucket
  2. Delete your detector via the Lookout for Metrics console.
  3. Delete the CloudFormation stacks in the following order (wait for one to complete before moving onto the next):
    1. custom-rs-connector-crawl
    2. custom-rs-connector
    3. CustomRedshiftConnector
    4. ProductionRedshiftDemo

Conclusion

You have now seen how to connect an Amazon Redshift database to Lookout for Metrics using the native Amazon Redshift Data APIs, CloudWatch Events, and Lambda functions. This approach allows you to create relevant datasets based on your information in Amazon Redshift to perform anomaly detection on your time series data in just a few minutes. If you can draft the SQL query to obtain the information, you can enable ML-powered anomaly detection on your data. From there, your anomalies should showcase anomalous events and help you understand how one anomaly may be caused or impacted by others, thereby reducing your time to understanding issues critical to your business or workload.


About the Authors

Chris King is a Principal Solutions Architect in Applied AI with AWS. He has a special interest in launching AI services and helped grow and build Amazon Personalize and Amazon Forecast before focusing on Amazon Lookout for Metrics. In his spare time he enjoys cooking, reading, boxing, and building models to predict the outcome of combat sports.

Alex Kim is a Sr. Product Manager for Amazon Forecast. His mission is to deliver AI/ML solutions to all customers who can benefit from it. In his free time, he enjoys all types of sports and discovering new places to eat.

Query and visualize Amazon Redshift operational metrics using the Amazon Redshift plugin for Grafana

Post Syndicated from Sergey Konoplev original https://aws.amazon.com/blogs/big-data/query-and-visualize-amazon-redshift-operational-metrics-using-the-amazon-redshift-plugin-for-grafana/

Grafana is a rich interactive open-source tool by Grafana Labs for visualizing data across one or many data sources. It’s used in a variety of modern monitoring stacks, allowing you to have a common technical base and apply common monitoring practices across different systems. Amazon Managed Grafana is a fully managed, scalable, and secure Grafana-as-a-service solution developed by AWS in collaboration with Grafana Labs.

Amazon Redshift is the most widely used data warehouse in the cloud. You can view your Amazon Redshift cluster’s operational metrics on the Amazon Redshift console, use AWS CloudWatch, and query Amazon Redshift system tables directly from your cluster. The first two options provide a set of predefined general metrics and visualizations. The last one allows you to use the flexibility of SQL to get deep insights into the details of the workload. However, querying system tables requires knowledge of system table structures. To address that, we came up with a consolidated Amazon Redshift Grafana dashboard that visualizes a set of curated operational metrics and works on top of the Amazon Redshift Grafana data source. You can easily add it to an Amazon Managed Grafana workspace, as well as to any other Grafana deployments where the data source is installed.

This post guides you through a step-by-step process to create an Amazon Managed Grafana workspace and configure an Amazon Redshift cluster with a Grafana data source for it. Lastly, we show you how to set up the Amazon Redshift Grafana dashboard to visualize the cluster metrics.

Solution overview

The following diagram illustrates the solution architecture.

Architecture Diagram

The solution includes the following components:

  • The Amazon Redshift cluster to get the metrics from.
  • Amazon Managed Grafana, with the Amazon Redshift data source plugin added to it. Amazon Managed Grafana communicates with the Amazon Redshift cluster via the Amazon Redshift Data Service API.
  • The Grafana web UI, with the Amazon Redshift dashboard using the Amazon Redshift cluster as the data source. The web UI communicates with Amazon Managed Grafana via an HTTP API.

We walk you through the following steps during the configuration process:

  1. Configure an Amazon Redshift cluster.
  2. Create a database user for Amazon Managed Grafana on the cluster.
  3. Configure a user in AWS Single Sign-On (AWS SSO) for Amazon Managed Grafana UI access.
  4. Configure an Amazon Managed Grafana workspace and sign in to Grafana.
  5. Set up Amazon Redshift as the data source in Grafana.
  6. Import the Amazon Redshift dashboard supplied with the data source.

Prerequisites

To follow along with this walkthrough, you should have the following prerequisites:

  • An AWS account
  • Familiarity with the basic concepts of the following services:
    • Amazon Redshift
    • Amazon Managed Grafana
    • AWS SSO

Configure an Amazon Redshift cluster

If you don’t have an Amazon Redshift cluster, create a sample cluster before proceeding with the following steps. For this post, we assume that the cluster identifier is called redshift-demo-cluster-1 and the admin user name is awsuser.

  1. On the Amazon Redshift console, choose Clusters in the navigation pane.
  2. Choose your cluster.
  3. Choose the Properties tab.

Redshift Cluster Properties

To make the cluster discoverable by Amazon Managed Grafana, you must add a special tag to it.

  1. Choose Add tags. Redshift Cluster Tags
  2. For Key, enter GrafanaDataSource.
  3. For Value, enter true.
  4. Choose Save changes.

Redshift Cluster Tags

Create a database user for Amazon Managed Grafana

Grafana will be directly querying the cluster, and it requires a database user to connect to the cluster. In this step, we create the user redshift_data_api_user and apply some security best practices.

  1. On the cluster details page, choose Query data and Query in query editor v2.Query Editor v2
  2. Choose the redshift-demo-cluster-1 cluster we created previously.
  3. For Database, enter the default dev.
  4. Enter the user name and password that you used to create the cluster.
  5. Choose Create connection.Redshift SU
  6. In the query editor, enter the following statements and choose Run:
CREATE USER redshift_data_api_user PASSWORD '&lt;password&gt;' CREATEUSER;
ALTER USER redshift_data_api_user SET readonly TO TRUE;
ALTER USER redshift_data_api_user SET query_group TO 'superuser';

The first statement creates a user with superuser privileges necessary to access system tables and views (make sure to use a unique password). The second prohibits the user from making modifications. The last statement isolates the queries the user can run to the superuser queue, so they don’t interfere with the main workload.

In this example, we use service managed permissions in Amazon Managed Grafana and a workspace AWS Identity and Access Management (IAM) role as an authentication provider in the Amazon Redshift Grafana data source. We create the database user redshift_data_api_user using the AmazonGrafanaRedshiftAccess policy.

Configure a user in AWS SSO for Amazon Managed Grafana UI access

Two authentication methods are available for accessing Amazon Managed Grafana: AWS SSO and SAML. In this example, we use AWS SSO.

  1. On the AWS SSO console, choose Users in the navigation pane.
  2. Choose Add user.
  3. In the Add user section, provide the required information.

SSO add user

In this post, we select Send an email to the user with password setup instructions. You need to be able to access the email address you enter because you use this email further in the process.

  1. Choose Next to proceed to the next step.
  2. Choose Add user.

An email is sent to the email address you specified.

  1. Choose Accept invitation in the email.

You’re redirected to sign in as a new user and set a password for the user.

  1. Enter a new password and choose Set new password to finish the user creation.

Configure an Amazon Managed Grafana workspace and sign in to Grafana

Now you’re ready to set up an Amazon Managed Grafana workspace.

  1. On the Amazon Grafana console, choose Create workspace.
  2. For Workspace name, enter a name, for example grafana-demo-workspace-1.
  3. Choose Next.
  4. For Authentication access, select AWS Single Sign-On.
  5. For Permission type, select Service managed.
  6. Chose Next to proceed.AMG Workspace configure
  7. For IAM permission access settings, select Current account.AMG permission
  8. For Data sources, select Amazon Redshift.
  9. Choose Next to finish the workspace creation.Redshift to workspace

You’re redirected to the workspace page.

Next, we need to enable AWS SSO as an authentication method.

  1. On the workspace page, choose Assign new user or group.SSO new user
  2. Select the previously created AWS SSO user under Users and Select users and groups tables.SSO User

You need to make the user an admin, because we set up the Amazon Redshift data source with it.

  1. Select the user from the Users list and choose Make admin.
  2. Go back to the workspace and choose the Grafana workspace URL link to open the Grafana UI.AMG workspace
  3. Sign in with the user name and password you created in the AWS SSO configuration step.

Set up an Amazon Redshift data source in Grafana

To visualize the data in Grafana, we need to access the data first. To do so, we must create a data source pointing to the Amazon Redshift cluster.

  1. On the navigation bar, choose the lower AWS icon (there are two) and then choose Redshift from the list.
  2. For Regions, choose the Region of your cluster.
  3. Select the cluster from the list and choose Add 1 data source.Choose Redshift Cluster
  4. On the Provisioned data sources page, choose Go to settings.
  5. For Name, enter a name for your data source.
  6. By default, Authentication Provider should be set as Workspace IAM Role, Default Region should be the Region of your cluster, and Cluster Identifier should be the name of the chosen cluster.
  7. For Database, enter dev.
  8. For Database User, enter redshift_data_api_user.
  9. Choose Save & Test.Settings for Data Source

A success message should appear.

Data source working

Import the Amazon Redshift dashboard supplied with the data source

As the last step, we import the default Amazon Redshift dashboard and make sure that it works.

  1. In the data source we just created, choose Dashboards on the top navigation bar and choose Import to import the Amazon Redshift dashboard.Dashboards in the plugin
  2. Under Dashboards on the navigation sidebar, choose Manage.
  3. In the dashboards list, choose Amazon Redshift.

The dashboard appear, showing operational data from your cluster. When you add more clusters and create data sources for them in Grafana, you can choose them from the Data source list on the dashboard.

Clean up

To avoid incurring unnecessary charges, delete the Amazon Redshift cluster, AWS SSO user, and Amazon Managed Grafana workspace resources that you created as part of this solution.

Conclusion

In this post, we covered the process of setting up an Amazon Redshift dashboard working under Amazon Managed Grafana with AWS SSO authentication and querying from the Amazon Redshift cluster under the same AWS account. This is just one way to create the dashboard. You can modify the process to set it up with SAML as an authentication method, use custom IAM roles to manage permissions with more granularity, query Amazon Redshift clusters outside of the AWS account where the Grafana workspace is, use an access key and secret or AWS Secrets Manager based connection credentials in data sources, and more. You can also customize the dashboard by adding or altering visualizations using the feature-rich Grafana UI.

Because the Amazon Redshift data source plugin is an open-source project, you can install it in any Grafana deployment, whether it’s in the cloud, on premises, or even in a container running on your laptop. That allows you to seamlessly integrate Amazon Redshift monitoring into virtually all your existing Grafana-based monitoring stacks.

For more details about the systems and processes described in this post, refer to the following:


About the Authors

Sergey Konoplev is a Senior Database Engineer on the Amazon Redshift team. Sergey has been focusing on automation and improvement of database and data operations for more than a decade.

Milind Oke is a Data Warehouse Specialist Solutions Architect based out of New York. He has been building data warehouse solutions for over 15 years and specializes in Amazon Redshift.

Automate Amazon Redshift load testing with the AWS Analytics Automation Toolkit

Post Syndicated from Samir Kakli original https://aws.amazon.com/blogs/big-data/automate-amazon-redshift-load-testing-with-the-aws-analytics-automation-toolkit/

Amazon Redshift is a fast, fully managed, widely popular cloud data warehouse that powers the modern data architecture that empowers you with fast and deep insights and machine learning (ML) predictions using SQL across your data warehouse, data lake, and operational databases. A key differentiating factor of Amazon Redshift is its native integration with other AWS services, which makes it easy to build complete, comprehensive, and enterprise-level analytics applications. The AWS Analytics Automation Toolkit enables automatic provisioning and integration of not only Amazon Redshift, but database migration services like AWS Database Migration Service (AWS DMS) and the AWS Schema Conversion Tool (AWS SCT).

This post discusses new additions to the AWS Analytics Automation Toolkit, which enable you to perform advanced load testing on Amazon Redshift. This is accomplished by provisioning Apache JMeter as part of the analytics stack.

Solution overview

Apache JMeter is an open-source load testing application written in Java that you can use to load test web applications, backend server applications, databases, and more. In the database context, it’s an extremely valuable tool for repeating benchmark tests in a consistent manner, simulating concurrency workloads, and scalability testing on different database configurations.

For example, you can use JMeter to simulate a single business intelligence (BI) user or hundreds of BI users simultaneously running various SQL queries on an Amazon Redshift cluster for performance benchmarking, scalability, and throughput testing. Furthermore, you can rerun the same exact simulation on a different Amazon Redshift cluster that perhaps has twice as many nodes as the original cluster, to compare the price/performance ratio of each cluster.

Similarly, you can use JMeter to load test and assess the performance and throughput achieved for mixed extract, transform, and load (ETL) and BI workloads running on different Amazon Redshift cluster configurations.

For a deeper discussion of JMeter and its use for benchmarking Amazon Redshift, refer to Building high-quality benchmark tests for Amazon Redshift using Apache JMeter.

Although JMeter installation is a relatively straightforward process, consisting mainly of downloading and installing a Java virtual machine and JMeter, the thought of having to download, install, and set up any tool for benchmarking purposes can sometimes serve as a detractor for many. Starting from scratch for a test setup could also be intimidating.

The AWS Analytics Automation Toolkit now includes the option to automatically deploy JMeter on Amazon Elastic Compute Cloud (Amazon EC2) in the same virtual private cloud (Amazon VPC) as Amazon Redshift. This includes a dedicated Windows instance, with all required JMeter dependencies, such as JVM and a sample test plan, thereby easily enabling powerful load testing capabilities on Amazon Redshift. In this post, we demonstrate the use of the AWS Analytics Automation Toolkit for JMeter load tests on cloud benchmark data, using Amazon Redshift as a target environment.

This solution has the following features:

  • It deploys resources automatically, including JMeter
  • You can point JMeter to an existing Amazon Redshift cluster, or automatically create a new cluster
  • You can bring your own data and queries, or use a sample TPC dataset
  • You can easily customize the test plan into separate threads, each with different workloads and concurrency as needed

To use the AWS Analytics Automation Toolkit to run a JMeter load test, deploy the toolkit with the JMeter option, load data into your Amazon Redshift cluster, and customize the default test plan as you see fit.

The following diagram illustrates the solution architecture:

Prerequisites

Prior to deploying the AWS Analytics Automation Toolkit, complete the prerequisites and prepare the config file, user-config.json. For instructions, refer to Automate building an integrated analytics solution with AWS Analytics Automation Toolkit.

The config file has a new parameter called JMETER, at the top section. To provision a JMeter instance, enter the value CREATE for this parameter.

To provision a new Amazon Redshift cluster, enter the value CREATE for the REDSHIFT_ENDPOINT parameter. Then fill in values for the fields in the redshift section of the config file. You can use the sizing calculator on the Amazon Redshift console to recommend the correct cluster configuration based on your data size.

If you want load an industry-standard sample TPC-DS data (3TB) into your cluster, enter the value “Y” for the “loadTPCdata” parameter, under the redshift section.

To use an existing cluster, enter the endpoint of your cluster for the REDSHIFT_ENDPOINT parameter in the top section of the user-config.json file.

Deploy resources using the AWS Analytics Automation Toolkit

To deploy your resources, complete the following steps:

  1. Launch the toolkit as described in Automate building an integrated analytics solution with AWS Analytics Automation Toolkit.
  2. Create tables and ingest your test data into your Amazon Redshift cluster.
    • If you chose to load the sample TPC-DS 3TB data, this will take some time to load, so please allow for this. If you are loading your own data then you may do that at this point.

Launch JMeter

To launch JMeter, complete the following steps:

  1. Using RDP, log in to the JMeter EC2 Windows instance created by the AWS Analytics Automation Toolkit.
  2. Launch the JMeter GUI by choosing (double-clicking) the shortcut JMETER on the Windows Desktop.

In our experience, changing the JMeter Look and Feel option to Windows (instead of dark mode) results in increased JMeter stability, so we highly recommend making that change and choosing Yes to restart the GUI.

Customize the JMeter test plan

To customize the JMeter test plan, we modify the JDBC connection, and optionally modify the thread ramp-up schedule and optimize the SQL.

  1. Using the JMeter GUI, open the AWS Analytics Automation Toolkit’s default test plan file c:\JMETER\apache-jmeter-5.4.1\Redshift Load Test.jmx.
  2. Choose the test plan name and edit the JdbcUser value to the correct user name for your Amazon Redshift cluster.

If you used the CREATE cluster option, this value is the same as the master_user_name value in your user-config.json file.

  1. In JDBC connection, edit the DatabaseURL value and password with the correct values for your cluster.

If you used the CREATE cluster option, the password is kept in a secret named <stackname>-RedshiftPassword. You can find the endpoint by choosing the new Amazon Redshift cluster and copying the endpoint value on the upper right.

This test plan already has a initialization command set to turn off the result cache feature of Amazon Redshift: set enable_result_cache_for_session to off. No action is needed to configure this.

  1. Optionally, modify the thread ramp-up schedule.

This test plan uses the Ultimate Thread Group, which is automatically installed when you open the test plan. Each thread group contains a ramp-up schedule, as well as a query or set of queries. Modify these to according to your testing preferences and dataset. If you loaded the TPCDS dataset, the queries included by default in the three thread groups will work.

In the following example, Smallthread Group has four rows, each of which launches the specific number of sessions at staggered timings. The ramp-up time to achieve the maximum session count is 45 seconds, because the last thread doesn’t start until 15 seconds into the test, and has a 30-second start time. You can adjust the ramp-up schedule, as well as the hold duration and shutdown time, by editing, adding, or deleting rows in the Thread Schedule section. The graph is then automatically adjusted.

  1. Optionally, you can customize the SQL.

In the following example, we choose the JDBC request item under the same SmallThread Group, called SmallSQL, and review the query run by this thread group. If you added your own data, insert the query or queries you want to run for this thread group. Do the same for the medium and large thread groups, or delete or add thread groups as needed.

Run the test

Run the test plan by choosing the green arrow in the GUI.

Alternatively, enter the following command in a Windows command prompt to run JMeter in command line mode:

C:\JMETER\apache-jmeter-5.4.1\bin\jmeter -n -t RedshiftTPCDWTest.jmx -e -l test.out

Use case example: Evaluating concurrency scaling benefits

For our example use case, we want to determine how Amazon Redshift concurrency scaling benefits our workload performance. We can use the JMeter setup outlined in this post to quickly answer this question.

In the following example, we ran the sample test plan as is against the sample TPC-DS data, with 80 concurrent users across three thread groups. We ran the test first with concurrency scaling enabled, then reran it after disabling concurrency scaling on the Amazon Redshift cluster.

To monitor the results, open the Amazon Redshift console, choose Clusters in the navigation pane, and choose the cluster you’re using for the performance test. On the Cluster performance tab, you can monitor the CPU utilization of all the nodes in your cluster, as shown in the following screenshot.

On the Query monitoring tab, you can monitor the queue activity, as well as concurrency scaling activity of your cluster.

The preceding graphs cover two different tests with a 4-node ra3.16xlarge cluster. On the left side, concurrency scaling was enabled for the cluster, and on the right side it was disabled. In the test with concurrency scaling enabled, the queueing is less, and test completion duration is shorter.

Note that the test duration is the time to run the workload on Amazon Redshift, not to download query results.

Lastly, to review the actual test result query performance, you can download the file C:\JMETER\apache-jmeter-5.4.1\SummaryReportIndividualRecords.csv from the EC2 instance, and review the query performance for each thread. The following screenshot is a summary plot of the test results for this example, with and without concurrency scaling.

As the chart illustrates, concurrency scaling can significantly reduce the latency for your workloads, and is particularly useful for short bursts of activity on your application.

Conclusion

JMeter allows you to create a flexible and powerful load test for your Amazon Redshift clusters to assess the performance of the cluster. With the new capability in the AWS Analytics Automation Toolkit, you can provision and configure JMeter, along with a test plan, in a fraction of the time it would normally take.


About the Authors

Samir Kakli is an Analytics POC Specialist Solutions Architect based out of Florida. He is focused on helping customers quickly and effectively align Amazon Redshift’s capabilities to their business needs.

Asser Moustafa is an Analytics Specialist Solutions Architect at AWS based out of Dallas, Texas. He advises customers in the Americas on their Amazon Redshift and data lake architectures and migrations, starting from the POC stage to actual production deployment and maintenance.

Perform ETL operations using Amazon Redshift RSQL

Post Syndicated from Saman Irfan original https://aws.amazon.com/blogs/big-data/perform-etl-operations-using-amazon-redshift-rsql/

Amazon Redshift is a fast, scalable, secure, and fully managed cloud data warehouse that makes it simple and cost-effective to analyze all your data using standard SQL and your existing ETL (extract, transform, and load), business intelligence (BI), and reporting tools. Tens of thousands of customers use Amazon Redshift to process exabytes of data per day and power analytics workloads such as BI, predictive analytics, and real-time streaming analytics.

There are many ways to interact with Amazon Redshift. You can programmatically access data in your Amazon Redshift cluster by using the Amazon Redshift Data API, or you can use a web-based interface such as Amazon Redshift Query Editor V2 to author SQL queries. You can also interact with Amazon Redshift in interactive or batch mode via Amazon Redshift RSQL.
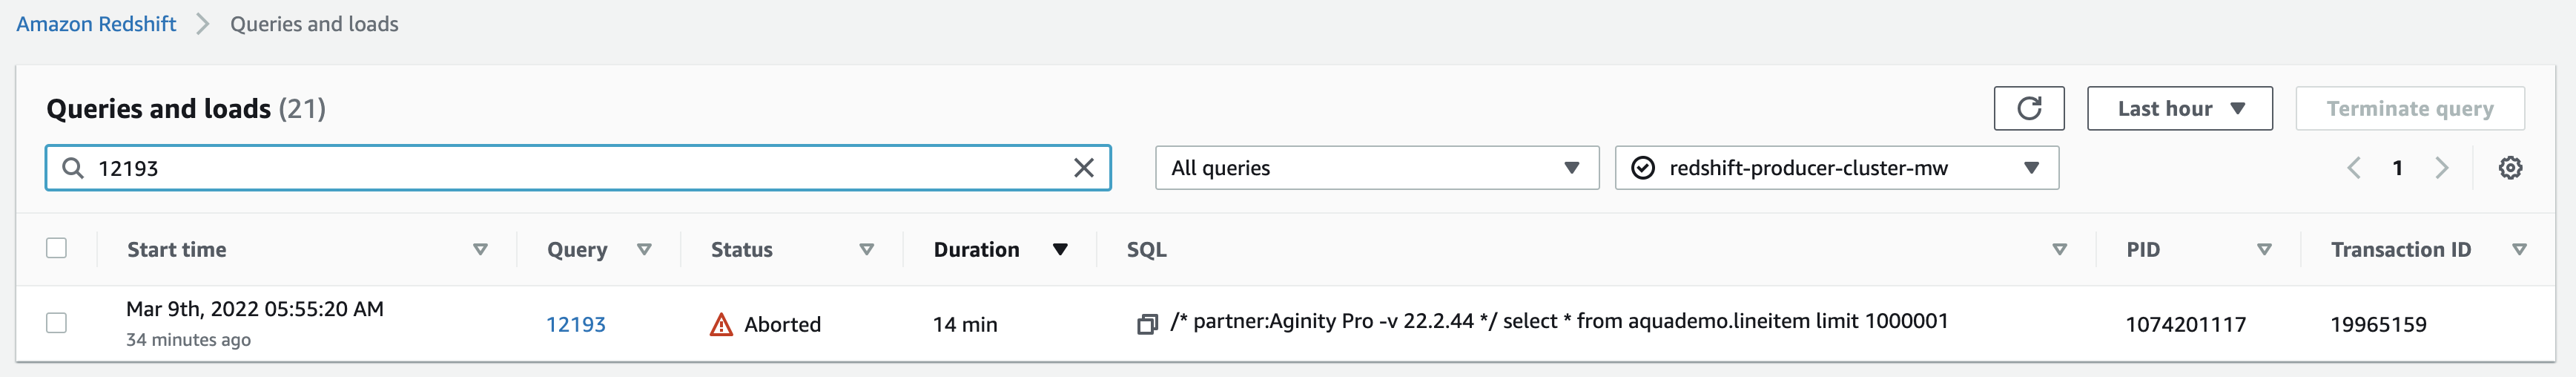
Previously, you had to use the PostgreSQL psql command line tool to interact with Amazon Redshift for simple use cases such as importing and exporting data to and from Amazon Redshift or submitting SQL in batch or interactive mode, or for advanced use cases such as performing ETL operations without writing complex ETL jobs.

Now you can use Amazon Redshift RSQL, a new command line tool to connect to an Amazon Redshift cluster and perform operations such as describe database objects, query data, view and export query results in various output file formats, run scripts that include both SQL and complex business logic, perform data cleansing and transformation operations using familiar SQL, and write ETL and ELT scripts using enhanced control flow and advanced error handling. Moreover, if you’re migrating from self-managed data warehousing engines such as Teradata to Amazon Redshift and using Teradata BTEQ (Basic Teradata Query) scripting for data automation, ETL or other tasks can now migrate to Amazon Redshift RSQL.

This post explains how to use Amazon Redshift RSQL for ETL, data cleansing and preparation, enhanced control flow, and exception and error handling.

Solution overview

Amazon Redshift RSQL enables you to connect to your Amazon Redshift cluster via a command line. It supports the capabilities of the PostgreSQL psql command line tool with an additional set of Amazon Redshift specific capabilities:

  • Describe properties or attributes of external tables in an AWS Glue catalog or Apache Hive metastore, external databases in Amazon RDS for PostgreSQL or Amazon Aurora PostgreSQL, and tables shared using Amazon Redshift data sharing
  • Use enhanced control flow commands such as \IF, \ELSEIF, \ELSE, \ENDIF, \GOTO, and \LABEL
  • Use single sign-on (SSO) authentication using ADFS, PingIdentity, Okta, Azure AD, or other SAML/JWT based identity providers (IdPs), as well as use browser-based SAML IdPs with multi-factor authentication (MFA)

The following are some commonly used commands in Amazon Redshift RSQL. We use these commands in this post to demonstrate different possible use cases using Amazon Redshift RSQL scripts.

  • \echo – Prints the specified string to the output.
  • \remark – An extension of the \echo command that has the ability to break the output over separate lines.
  • \goto – Skips all intervening commands and SQL statements and resume the processing at the specified \LABEL in sequence. The \LABEL must be a forward reference. You can’t jump to a \LABEL that lexically precedes the \GOTO.
  • \label – Establishes an entry point for running the program as the target for a \GOTO command.
  • \exit – Stops running Amazon Redshift RSQL. You can also specify an optional exit code.
  • \q – Logs off database sessions and exits Amazon Redshift RSQL.

Prerequisites

The following are the prerequisites for using Amazon Redshift RSQL and perform the steps in this post:

  • An AWS account
  • Linux, Windows, or MacOs operating system (Amazon Redshift RSQL is available for these operating systems)
  • An Amazon Redshift cluster
  • SQL knowledge

Additionally, complete the following prerequisite steps:

  1. Install Amazon Redshift RSQL on your local machine. For instructions, refer to Getting started with Amazon Redshift RSQL.
  2. Connect to the Amazon Redshift cluster.
  3. Create the orders and orders_summary tables using the following DDL statements:
    create table orders (
      O_ORDERKEY bigint NOT NULL,
      O_CUSTKEY bigint,
      O_ORDERSTATUS varchar(1),
      O_TOTALPRICE decimal(18,4),
      O_ORDERDATE Date,
      O_ORDERPRIORITY varchar(15),
      O_CLERK varchar(15),
      O_SHIPPRIORITY Integer,
      O_COMMENT varchar(79))
    distkey (O_ORDERKEY)
    sortkey (O_ORDERDATE);
    
    CREATE TABLE orders_summary 
    ( o_orderkey bigint, 
     o_custkey bigint, 
     o_orderstatus character varying(1),
     o_totalprice integer,
     target_information character varying(14),
     rank character varying(15),
     description character varying(15)
    ) DISTSTYLE AUTO;

Import data into the Amazon Redshift cluster

There are multiple ways to load data into Amazon Redshift tables, including using Amazon Redshift RSQL. In this section, we review the syntax and an example of the Amazon Redshift RSQL script to load data into an Amazon Redshift table using the COPY command.

We use the following syntax:

COPY <TABLE> from <location> 
iam_role <arn>
region <region>;

We provide the following parameters:

  • <location> – The location of the source data to be loaded into the target table
  • <arn> – The AWS Identity and Access Management (IAM) role for accessing the data
  • <region> – The AWS Region of the source data

In the following example Amazon Redshift RSQL script, we load data from an Amazon Simple Storage Service (Amazon S3) bucket location into the orders table:

\echo 'Job started' 
  copy orders from 's3://redshift-immersionday-labs/data/orders/orders.tbl.'
  iam_role default
  region 'us-west-2' lzop delimiter '|' COMPUPDATE PRESET;
\echo 'Job Ended'
\exit 0 

Enhanced control flow

You can use Amazon Redshift RSQL to define programmatic enhanced control flow and conditional blocks in your ETL script. We use the following syntax:

\if <condition> 
  <code_block1>
\else
  <code_block2>
\endif

The syntax includes the following components:

  • <condition> –The conditional statement
  • <code_block1> – The code block to run when the condition is met
  • <code_block2> – The code block to run when the condition is not met

In the following example script, we perform some conditional checks using if, elseif, and else commands based on the count of records from the orders table, and we display some messages based on the record count value:

\echo 'Job started'
Select count(*)  from orders \gset
select :count as count;
\if :count < 76000000 
  \echo 'Orders are less than target'
\elseif :count =76000000
  \echo 'Order met the target'
\else :count > 76000000
  \echo 'Orders exceeded the target'
\endif
\echo 'Job Ended' 
\exit 0  

Error handling

You can use Amazon Redshift RSQL to define exception handling blocks in your in ETL script to handle various user-defined and system-generated error scenarios that you might encounter while running the ETL process.

The following are some of the error handling options supported in Amazon Redshift RSQL:

  • :ACTIVITYCOUNT – This variable is similar to the psql variable ROW_COUNT, which returns the number of rows affected by last SQL statement. However, ACTIVITYCOUNT reports the affected row count for SELECT, COPY, and UNLOAD statements, which ROW_COUNT does not. For SQL statements returning data, ACTIVITYCOUNT specifies the number of rows returned to Amazon Redshift RSQL from the database.
  • :ERRORCODE – This variable contains the return code for the last submitted SQL statement to the database. Error code 0 specifies that SQL statement completed without any errors.
  • :ERRORLEVEL – This variable is used to assign severity levels to errors. You can use these severity levels to determine a course of action. The default value is ON.
  • :MAXERROR – This variable designates a maximum error severity level beyond which Amazon Redshift RSQL halts job processing. If SQL statements in Amazon Redshift RSQL scripts produce an error severity level greater than the designated maxerror value, Amazon Redshift RSQL immediately exits.
  • :LAST_ERROR_MESSAGE – This variable contains the error message of the most recent failed query.

We use the following syntax:

\if :ERROR <> 0 
  \echo :<ERRORCODE>
  \echo :<LAST_ERROR_MESSAGE>
  \goto <codeblock1>
\else
  \goto Y
\endif

The syntax includes the following information:

  • <ERRORCODE> –The error code number
  • <LAST_ERROR_MESSAGE> – The error message of the most recent failed query
  • <code_block1> – The code block to run when the error condition is met
  • <code_block2> – The code block to run when the error condition is not met

In the following example script, we create the orders_staging table and copy records into the table from an Amazon S3 location. The script also contains an exception handling section for both the table creation and copy process to handle the possible errors encountered during the process.

\echo `date`
\echo 'Job started'
DROP TABLE IF EXISTS orders_staging;

create table orders_staging (
O_ORDERKEY bigint NOT NULL,
O_CUSTKEY bigint,
O_ORDERSTATUS varchar(1),
O_TOTALPRICE decimal(18,4),
O_ORDERDATE Date,
O_ORDERPRIORITY varchar(15),
O_CLERK varchar(15),
O_SHIPPRIORITY Integer,
O_COMMENT varchar(79))
distkey (O_ORDERKEY)
sortkey (O_ORDERDATE);

\if :ERROR <> 0 
  \echo :ERRORCODE
  \remark :LAST_ERROR_MESSAGE
  \goto QUIT_JOB
\else
  \remark '***Orders_Staging Table Created Successfully****'
  \goto COPY_DATA
\endif

\label COPY_DATA
 copy orders_staging from 's3://redshift-immersionday-  labs/data/orders/orders.tbl.'
 iam_role default
 region 'us-west-2' lzop delimiter '|' COMPUPDATE PRESET;

\if :ERROR <> 0
  \echo :ERRORCODE
  \remark :LAST_ERROR_MESSAGE
  \goto QUIT_JOB
\else 
  \remark '****Data Copied Successfully****'
\endif

\echo `date`
\echo 'Job Ended'
\exit 0 

\label QUIT_JOB
 \echo `date`
 \echo 'Job Failed'
 \exit 1 

Data transformation and preparation

You can perform some common data preparation and transformation operations on your dataset using SQL statements in the Amazon Redshift RSQL ETL script. In this section, we demonstrate data transformation and preparation operations such as casting, new data column creation, and splitting an input column into multiple columns.

We use industry standard SQL statements for transforming and preparing data for downstream consumption.

In the following example script, we use a SQL statement to transform the data from the orders_staging table and insert it into the orders_summary table:

\echo `date`
\echo 'Job started'

insert into orders_summary 
(o_orderkey,
o_custkey,
o_orderstatus,
o_totalprice,
target_information,
rank,
description)
select
o_orderkey,
o_custkey,
o_orderstatus,
o_totalprice::int,
case 
when o_totalprice < 200000
then 'Target Missed'
when o_totalprice = 200000
then 'Target Met'
when o_totalprice > 200000
then 'Target Exceeds'
end as "Target_Information",
split_part (o_orderpriority,'-',1) as RANK, 
split_part (o_orderpriority,'-',2) as DESCRIPTION
from orders_staging; 

\if :ERROR <> 0 or :ACTIVITYCOUNT=0
 \echo :ERRORCODE
 \remark :LAST_ERROR_MESSAGE
 \goto QUIT_JOB
\else
 \remark 'Data Inserted into Summary Orders Table'
\endif

\echo `date`
\echo 'Job Ended'
\exit 0 

\label QUIT_JOB
 \echo `date`
 \echo 'Job Failed'
 \exit 1 

Export data from an Amazon Redshift cluster and output file formatting options

You can use Amazon Redshift RSQL to extract data from one or multiple Amazon Redshift tables and write to your disk for consumption by downstream applications. Amazon Redshift RSQL uses the \EXPORT option to export the result of query to an output file.

The following are some of the useful output formating options supported in RSQL:

  • \rset rformat on – This command is required for all the formatting commands to take effect.
  • \pset format – Formats can include aligned, AsciiDoc, CSV, HTML, LaTeX, LaTeX longtable, troff-ms, unaligned, and wrapped.
  • \pset border – This option specifies border information for output data. Value 0 means no border, 1 means internal dividing lines, and 2 means table frame.
  • \rset heading – This command adds the specified heading to the output result.
  • \rset rtitle – This command adds the specified heading as well as current system date of the client computer.
  • \rset titledashes on/off – This command specifies whether to print a line of dash characters between the column names and column data returned for the SQL query.
  • \rset width – This command specifies the target width for each line in a report
  • \t – This command turns off printing column names as well as result row count at the end of the output (footers).

We use the following syntax:

\export report file=<'FilePath/Filename'>
\rset rformat on
\pset format wrapped
\pset border 2
\rset heading ‘This is Heading’
\rset width 50
\rset titledashes on
<SQL Query>
\export reset

We provide the following information:

  • <‘FilePath/Filename’> – The file name and path for the output file
  • <SQL Query> – The SQL query to run

In the following example script, we export the data from the orders_summary table using a SQL query and write it into the orders.txt text file on the local machine:

\echo `date`
\echo 'Job started'

\export report file='/<FilePath>/orders.txt'
\rset rformat on
\pset format wrapped
\rset width 50
\rset titledashes on
select * from orders_summary limit 100;

\export reset
\echo 'Job Ended'
\echo `date`
\exit 0 

Automate the Amazon Redshift RSQL ETL script

One of the options to automate Amazon Redshift RSQL scripts to run on a specific schedule is via shell scripting. You can schedule the shell script via a CRON job, a command line utility.

We use the following syntax:

#!/bin/sh
rsql -D awsuser -f <RSQL_SCRIPT> <LOG_FILE>

We provide the following information:

  • <RSQL_SCRIPT> – The SQL scripts to un
  • <LOG_FILE> – The output log file

In the following example shell script, we run the Amazon Redshift RSQL script that we created and write the output log in a log file in the local machine. You can schedule the shell script via a CRON job.

#!/bin/sh
SCRIPTS_DIR="<SCRIPTS_DIR>"
LOG_DIR="<LOG_DIR>"

RSQL_SCRIPT="${SCRIPTS_DIR}/<RSQL_SCRIPT>.sql"
LOG_FILE="${LOG_DIR}/test_rsql.log"

touch $LOG_FILE

rsql -D awsuser -f ${RSQL_SCRIPT} > ${LOG_FILE}

Clean up

To avoid incurring future charges, stop the Amazon Redshift cluster created for the purpose of this post.

Conclusion

In this post, we explained how to use Amazon Redshift RSQL to perform ETL operations. We also demonstrated how to implement advanced error handling and enhanced control flow in your Amazon Redshift RSQL ETL script.

If you’re using scripts via the psql command line client on Amazon Redshift, you can operate on Amazon Redshift RSQL with no modification. If you’re migrating your Teradata BTEQ scripts to Amazon Redshift RSQL, you can use the AWS Schema Conversion Tool (AWS SCT) to automatically convert BTEQ scripts to Amazon Redshift RSQL scripts.

To learn more, refer to Amazon Redshift RSQL.


About the Authors

Saman Irfan is a Specialist Solutions Architect at Amazon Web Services. She focuses on helping customers across various industries build scalable and high-performant analytics solutions. Outside of work, she enjoys spending time with her family, watching TV series, and learning new technologies.

Sudipta Bagchi is a Specialist Solutions Architect at Amazon Web Services. He has over 12 years of experience in data and analytics, and helps customers design and build scalable and high-performant analytics solutions. Outside of work, he loves running, traveling, and playing cricket.

ETL orchestration using the Amazon Redshift Data API and AWS Step Functions with AWS SDK integration

Post Syndicated from Jason Pedreza original https://aws.amazon.com/blogs/big-data/etl-orchestration-using-the-amazon-redshift-data-api-and-aws-step-functions-with-aws-sdk-integration/

Extract, transform, and load (ETL) serverless orchestration architecture applications are becoming popular with many customers. These applications offers greater extensibility and simplicity, making it easier to maintain and simplify ETL pipelines. A primary benefit of this architecture is that we simplify an existing ETL pipeline with AWS Step Functions and directly call the Amazon Redshift Data API from the state machine. As a result, the complexity for the ETL pipeline is reduced.

As a data engineer or an application developer, you may want to interact with Amazon Redshift to load or query data with a simple API endpoint without having to manage persistent connections. The Amazon Redshift Data API allows you to interact with Amazon Redshift without having to configure JDBC or ODBC connections. This feature allows you to orchestrate serverless data processing workflows, design event-driven web applications, and run an ETL pipeline asynchronously to ingest and process data in Amazon Redshift, with the use of Step Functions to orchestrate the entire ETL or ELT workflow.

This post explains how to use Step Functions and the Amazon Redshift Data API to orchestrate the different steps in your ETL or ELT workflow and process data into an Amazon Redshift data warehouse.

AWS Lambda is typically used with Step Functions due to its flexible and scalable compute benefits. An ETL workflow has multiple steps, and the complexity may vary within each step. However, there is an alternative approach with AWS SDK service integrations, a feature of Step Functions. These integrations allow you to call over 200 AWS services’ API actions directly from your state machine. This approach is optimal for steps with relatively low complexity compared to using Lambda because you no longer have to maintain and test function code. Lambda functions have a maximum timeout of 15 minutes; if you need to wait for longer-running processes, Step Functions standard workflows allows a maximum runtime of 1 year.

You can replace steps that include a single process with a direct integration between Step Functions and AWS SDK service integrations without using Lambda. For example, if a step is only used to call a Lambda function that runs a SQL statement in Amazon Redshift, you may remove the Lambda function with a direct integration to the Amazon Redshift Data API’s SDK API action. You can also decouple Lambda functions with multiple actions into multiple steps. An implementation of this is available later in this post.

We created an example use case in the GitHub repo ETL Orchestration using Amazon Redshift Data API and AWS Step Functions that provides an AWS CloudFormation template for setup, SQL scripts, and a state machine definition. The state machine directly reads SQL scripts stored in your Amazon Simple Storage Service (Amazon S3) bucket, runs them in your Amazon Redshift cluster, and performs an ETL workflow. We don’t use Lambda in this use case.

Solution overview

In this scenario, we simplify an existing ETL pipeline that uses Lambda to call the Data API. AWS SDK service integrations with Step Functions allow you to directly call the Data API from the state machine, reducing the complexity in running the ETL pipeline.

The entire workflow performs the following steps:

  1. Set up the required database objects and generate a set of sample data to be processed.
  2. Run two dimension jobs that perform SCD1 and SCD2 dimension load, respectively.
  3. When both jobs have run successfully, the load job for the fact table runs.
  4. The state machine performs a validation to ensure the sales data was loaded successfully.

The following architecture diagram highlights the end-to-end solution:

We run the state machine via the Step Functions console, but you can run this solution in several ways:

You can deploy the solution with the provided CloudFormation template, which creates the following resources:

  • Database objects in the Amazon Redshift cluster:
    • Four stored procedures:
      • sp_setup_sales_data_pipeline() – Creates the tables and populates them with sample data
      • sp_load_dim_customer_address() – Runs the SCD1 process on customer_address records
      • sp_load_dim_item() – Runs the SCD2 process on item records
      • sp_load_fact_sales (p_run_date date) – Processes sales from all stores for a given day
    • Five Amazon Redshift tables:
      • customer
      • customer_address
      • date_dim
      • item
      • store_sales
  • The AWS Identity and Access Management (IAM) role StateMachineExecutionRole for Step Functions to allow the following permissions:
    • Federate to the Amazon Redshift cluster through getClusterCredentials permission avoiding password credentials
    • Run queries in the Amazon Redshift cluster through Data API calls
    • List and retrieve objects from Amazon S3
  • The Step Functions state machine RedshiftETLStepFunction, which contains the steps used to run the ETL workflow of the sample sales data pipeline

Prerequisites

As a prerequisite for deploying the solution, you need to set up an Amazon Redshift cluster and associate it with an IAM role. For more information, see Authorizing Amazon Redshift to access other AWS services on your behalf. If you don’t have a cluster provisioned in your AWS account, refer to Getting started with Amazon Redshift for instructions to set it up.

When the Amazon Redshift cluster is available, perform the following steps:

  1. Download and save the CloudFormation template to a local folder on your computer.
  2. Download and save the following SQL scripts to a local folder on your computer:
    1. sp_statements.sql – Contains the stored procedures including DDL and DML operations.
    2. validate_sql_statement.sql – Contains two validation queries you can run.
  3. Upload the SQL scripts to your S3 bucket. The bucket name is the designated S3 bucket specified in the ETLScriptS3Path input parameter.
  4. On the AWS CloudFormation console, choose Create stack with new resources and upload the template file you downloaded in the previous step (etl-orchestration-with-stepfunctions-and-redshift-data-api.yaml).
  5. Enter the required parameters and choose Next.
  6. Choose Next until you get to the Review page and select the acknowledgement check box.
  7. Choose Create stack.
  8. Wait until the stack deploys successfully.

When the stack is complete, you can view the outputs, as shown in the following screenshot:

Run the ETL orchestration

After you deploy the CloudFormation template, navigate to the stack detail page. On the Resources tab, choose the link for RedshiftETLStepFunction to be redirected to the Step Functions console.

The RedshiftETLStepFunction state machine runs automatically, as outlined in the following workflow:

  1. read_sp_statement and run_sp_deploy_redshift – Performs the following actions:
    1. Retrieves the sp_statements.sql from Amazon S3 to get the stored procedure.
    2. Passes the stored procedure to the batch-execute-statement API to run in the Amazon Redshift cluster.
    3. Sends back the identifier of the SQL statement to the state machine.
  2. wait_on_sp_deploy_redshift – Waits for at least 5 seconds.
  3. run_sp_deploy_redshift_status_check – Invokes the Data API’s describeStatement to get the status of the API call.
  4. is_run_sp_deploy_complete – Routes the next step of the ETL workflow depending on its status:
    1. FINISHED – Stored procedures are created in your Amazon Redshift cluster.
    2. FAILED – Go to the sales_data_pipeline_failure step and fail the ETL workflow.
    3. All other status – Go back to the wait_on_sp_deploy_redshift step to wait for the SQL statements to finish.
  5. setup_sales_data_pipeline – Performs the following steps:
    1. Initiates the setup stored procedure that was previously created in the Amazon Redshift cluster.
    2. Sends back the identifier of the SQL statement to the state machine.
  6. wait_on_setup_sales_data_pipeline – Waits for at least 5 seconds.
  7. setup_sales_data_pipeline_status_check – Invokes the Data API’s describeStatement to get the status of the API call.
  8. is_setup_sales_data_pipeline_complete – Routes the next step of the ETL workflow depending on its status:
    1. FINISHED – Created two dimension tables (customer_address and item) and one fact table (sales).
    2. FAILED – Go to the sales_data_pipeline_failure step and fail the ETL workflow.
    3. All other status – Go back to the wait_on_setup_sales_data_pipeline step to wait for the SQL statements to finish.
  9. run_sales_data_pipeline – LoadItemTable and LoadCustomerAddressTable are two parallel workflows that Step Functions runs at the same time. The workflows run the stored procedures that were previously created. The stored procedure loads the data into the item and customer_address tables. All other steps in the parallel sessions follow the same concept as described previously. When both parallel workflows are complete, run_load_fact_sales runs.
  10. run_load_fact_sales – Inserts data into the store_sales table that was created in the initial stored procedure.
  11. Validation – When all the ETL steps are complete, the state machine reads a second SQL file from Amazon S3 (validate_sql_statement.sql) and runs the two SQL statements using the batch_execute_statement method.

The implementation of the ETL workflow is idempotent. If it fails, you can retry the job without any cleanup. For example, it recreates the stg_store_sales table each time, then deletes the target table store_sales with the data for the particular refresh date each time.

The following diagram illustrates the state machine workflow:

In this example, we use the task state resource arn:aws:states:::aws-sdk:redshiftdata:[apiAction] to call the corresponding Data API action. The following table summarizes the Data API actions and their corresponding AWS SDK integration API actions.

Amazon Redshift Data API Actions AWS SDK Integrations API Actions
BatchExecuteStatement batchExecuteStatement
ExecuteStatement executeStatement
DescribeStatement describeStatement
CancelStatement cancelStatement
GetStatementResult getStatementResult
DescribeTable describeTable
ListDatabases listDatabases
ListSchemas listSchemas
ListStatements listStatements
ListTables listTables

To use AWS SDK integrations, you specify the service name and API call, and, optionally, a service integration pattern. The AWS SDK action is always camel case, and parameter names are Pascal case. For example, you can use the Step Functions action batchExecuteStatement to run multiple SQL statements in a batch as a part of a single transaction on the Data API. The SQL statements can be SELECT, DML, DDL, COPY, and UNLOAD.

Validate the ETL orchestration

The entire ETL workflow takes approximately 1 minute to run. The following screenshot shows that the ETL workflow completed successfully.

When the entire sales data pipeline is complete, you may go through the entire execution event history, as shown in the following screenshot.

Schedule the ETL orchestration

After you validate the sales data pipeline, you may opt to run the data pipeline on a daily schedule. You can accomplish this with Amazon EventBridge.

  1. On the EventBridge console, create a rule to run the RedshiftETLStepFunction state machine daily.
  2. To invoke the RedshiftETLStepFunction state machine on a schedule, choose Schedule and define the appropriate frequency needed to run the sales data pipeline.
  3. Specify the target state machine as RedshiftETLStepFunction and choose Create.

You can confirm the schedule on the rule details page.

Clean up

Clean up the resources created by the CloudFormation template to avoid unnecessary cost to your AWS account. You can delete the CloudFormation stack by selecting the stack on the AWS CloudFormation console and choosing Delete. This action deletes all the resources it provisioned. If you manually updated a template-provisioned resource, you may see some issues during cleanup; you need to clean these up independently.

Limitations

The Data API and Step Functions AWS SDK integration offers a robust mechanism to build highly distributed ETL applications within minimal developer overhead. Consider the following limitations when using the Data API and Step Functions:

Conclusion

In this post, we demonstrated how to build an ETL orchestration using the Amazon Redshift Data API and Step Functions with AWS SDK integration.

To learn more about the Data API, see Using the Amazon Redshift Data API to interact with Amazon Redshift clusters and Using the Amazon Redshift Data API.


About the Authors

Jason Pedreza is an Analytics Specialist Solutions Architect at AWS with over 13 years of data warehousing experience. Prior to AWS, he built data warehouse solutions at Amazon.com. He specializes in Amazon Redshift and helps customers build scalable analytic solutions.

Bipin Pandey is a Data Architect at AWS. He loves to build data lake and analytics platforms for his customers. He is passionate about automating and simplifying customer problems with the use of cloud solutions.

David Zhang is an AWS Solutions Architect who helps customers design robust, scalable, and data-driven solutions across multiple industries. With a background in software development, David is an active leader and contributor to AWS open-source initiatives. He is passionate about solving real-world business problems and continuously strives to work from the customer’s perspective. Feel free to connect with him on LinkedIn.

How to evaluate the benefits of AQUA for your Amazon Redshift workloads

Post Syndicated from Dinesh Kumar original https://aws.amazon.com/blogs/big-data/how-to-evaluate-the-benefits-of-aqua-for-your-amazon-redshift-workloads/

Amazon Redshift is the cloud data warehouse of choice for tens of thousands of customers, who use it to analyze exabytes of data to gain business insights. Customers have been asking us for better performance at scale as the volume, variety, velocity, and veracity of their data grows. We have added several features to Amazon Redshift that enable you to get up to three times better price performance with Amazon Redshift than other cloud data warehouses.

In addition, we launched AQUA (Advanced Query Accelerator) for Amazon Redshift to help you cost-effectively run analytics at the new scale of data. AQUA is a distributed and hardware-accelerated cache that enables Amazon Redshift to run an order of magnitude faster than other enterprise cloud data warehouses by automatically boosting certain types of queries. AQUA uses AWS-designed processors with AWS Nitro chips adapted to speed up data encryption and compression, and custom analytics processors, implemented in FPGAs, to accelerate operations such as scans, filtering, and aggregation. AQUA is available with the RA3.16xlarge, RA3.4xlarge, and RA3.xlplus nodes at no additional charge and requires no code changes. You can enable AQUA for your existing Amazon Redshift RA3 clusters or launch a new AQUA-enabled RA3 cluster via the AWS Management Console, API, or AWS Command Line Interface (AWS CLI). To learn more about AQUA, see Working with AQUA (Advanced Query Accelerator).

This post walks you through steps to quantify expected benefits from AQUA for Amazon Redshift for your workloads. We cover the methodology used for testing AQUA and share the scripts, a sample dataset, and queries so you can test AQUA in your own environment. We have published scripts on GitHub (along with a README file), which you need as you follow the steps in this post. Download all scripts to your working directory from where you intend to connect to your Redshift clusters.

Solution overview

At a high-level, the AQUA test process involves the following steps:

  1. Create a test cluster to evaluate AQUA and make sure that AQUA is turned on. For instructions, see Working with AQUA (Advanced Query Accelerator).
  2. Analyze your workload for AQUA and capture eligible queries. To learn more about the types of queries accelerated by AQUA, refer to When does Amazon Redshift use AQUA to run queries?
  3. Run the workload with AQUA activated and deactivated on your test cluster.
  4. Compare performance results.

This approach is a straightforward yet practical way to measure the performance gain you can expect to get for your workload by turning on AQUA.

With the exception of one workload parsing and analyzing script (aqua_capture_query.sh), you can run the rest of the scripts on a test cluster. We recommend using a test cluster to minimize the impact to your production cluster.

Create a test cluster

Create a snapshot from a production cluster that has read-heavy workloads and restore it as test cluster.

Analyze your workload and capture eligible queries

Run aqua_capture_query.sh on the production cluster to determine the queries suitable for acceleration by AQUA. We recommend choosing workloads with SELECT queries that use LIKE or SIMILAR TO functions in the WHERE clause and scan, filter, and aggregate large datasets. aqua_capture_query.sh scans the query history on your production cluster and captures queries that AQUA can accelerate.

The script runtime may exceed several minutes depending on the selected time interval (analyze_starttime and analyze_endtime), size of the cluster, and workload complexity. We suggest restricting the script runtime by limiting the time interval to the lesser of your workload runtime or 3 hours. Alternately, you can evaluate AQUA using the Amazon Reviews sample dataset, which we demonstrate later in this post.

aqua_capture_query.sh saves an output file named aqua_eligible_queries to your working directory and contains a subset of most suitable AQUA-eligible queries.

The following is a sample output by the script:

select count(*) from amazon_reviews where product_title SIMILAR TO '%lap%' group by star_rating ORDER BY star_rating desc;
select count(*) from amazon_reviews where product_title ilike '%e%|%E%' or customer_ID like '3%__%45__3';

If your workload history doesn’t have enough AQUA-eligible queries, the script reports no eligible queries found. If this happens, run the script with different date/time parameters. If you still don’t see any queries, you can try using the sample dataset and queries provided in this post. For more information about AQUA-eligible queries, refer to When does Amazon Redshift use AQUA to run queries?

Run the workload on your test cluster

Run aqua_execute_query.sh on your test cluster. The script runs the captured queries on your cluster repeatedly to get consistent performance by reducing the impact of runtime difference due to environmental factors with AQUA activated and deactivated. The script records the start date/time and end date/time to a file named workload_datetime.txt in your working directory.

Compare performance results

When aqua_execute_query.sh script is complete, run aqua_perf_compare.sh, which generates a CSV file named aqua_benefit in your working directory. The following table summarizes the sample output.

Query ID Amazon Redshift with AQUA turned on Query ID Amazon Redshift with AQUA turned off Runtime in seconds with AQUA turned on Runtime in seconds with AQUA turned off Speedup
(Column C/Column B)
1153194 1153370 2.7 59.4 22.0
1153214 1153456 22.8 104.9 4.6
334629 334631 1.66643 35.8 22.25
334850 334672 1.71297 26.9 15.7
334984 334998 1.85051 26.9 14.5
334830 334793 6.47884 87.2 13.4
334828 334740 6.6974 87.1 13

This table shows the query identifiers and runtime of the queries with AQUA activated and deactivated. You can compare the benefits offered by AQUA by reviewing the speedup column.

Example use case with the Amazon Reviews dataset

To test AQUA with the Amazon Reviews sample dataset, perform the following steps:

  1. Create a two-node RA3.4xlarge cluster by issuing the following command:
    aws redshift create-cluster --cluster-identifier test-amazon-reviews --node-type ra3.4xlarge --number-of-nodes 2 --master-username adminuser --master-user-password <xxpasswordxx> --aqua-configuration-status enabled

  2. Create a test database on our Amazon Redshift cluster by issuing the following command:
    CREATE DATABASE TestDB;

  3. Load the table with the Amazon Reviews dataset by running the script load_amazon_sentiments_data.sql.
  4. Run a few AQUA-eligible queries (similar to the following) multiple times with and without AQUA activated using the script execute_test_queries.sh:
    select count(*) from amazon_reviews WHERE product_title SIMILAR TO '%lap%' or product_title SIMILAR TO '%hope%' or product_title SIMILAR TO '%nice%' or product_title SIMILAR TO '%soa%';

More evaluation queries are available on the GitHub repo.

  1. Run aqua_perf_compare.sh on the test cluster.

The following table shows that AQUA accelerated the queries 5–22 times faster.

Query ID Amazon Redshift with AQUA turned on Query ID Amazon Redshift with AQUA turned off Runtime in seconds with AQUA turned on Runtime in seconds with AQUA turned off Speedup
(Column C/Column B)
364202 364217 2.33411 51.56207 22.09073
334984 334998 1.85051 26.9 14.5
334830 334793 6.47884 87.2 13.4
334828 334740 6.6974 87.1 13

Summary

This post provides a straightforward yet practical way to measure the performance gain you can expect to get for your workload by turning on AQUA. You can use the scripts provided and test with your own dataset and queries, or use the sample dataset and queries to determine AQUA’s impact.

We continue to invest and launch new capabilities like AQUA for Amazon Redshift to make sure Amazon Redshift continues to improve as your data warehouse needs grow. For AQUA, we continue to add hardware acceleration for more SQL operators, functions, predicates, data types, and file formats so more scans, filters, and aggregations can be pushed down to AQUA. Pushdowns to AQUA remain transparent so Amazon Redshift decides when to push queries down to AQUA to take advantage of hardware acceleration. And when queries don’t get pushed down to AQUA, they continue to run on Amazon Redshift as before.

We invite you to test AQUA for yourself and share the findings.


About the Authors

Dinesh Kumar is a Database Engineer at AWS focusing on Amazon AQUA. He works with customers to build highly scalable data warehouse and high performant database solutions. Outside work, he enjoys gardening and spending time with his family.

Manan Goel is a Product Go-To-Market Leader for AWS Analytics Services including Amazon Redshift & AQUA at AWS. He has more than 25 years of experience and is well versed with databases, data warehousing, business intelligence, and analytics. Manan holds a MBA from Duke University and a BS in Electronics & Communications engineering.

Export JSON data to Amazon S3 using Amazon Redshift UNLOAD

Post Syndicated from Dipankar Kushari original https://aws.amazon.com/blogs/big-data/export-json-data-to-amazon-s3-using-amazon-redshift-unload/

Amazon Redshift is a fast, scalable, secure, and fully managed cloud data warehouse that makes it simple and cost-effective to analyze all your data using standard SQL. Amazon Redshift offers up to three times better price performance than any other cloud data warehouse. Tens of thousands of customers use Amazon Redshift to process exabytes of data per day and power analytics workloads such as high-performance business intelligence (BI) reporting, dashboarding applications, data exploration, and real-time analytics.

As the amount of data generated by IoT devices, social media, and cloud applications continues to grow, organizations are looking to easily and cost-effectively analyze this data with minimal time-to-insight. A vast amount of this data is available in semi-structured format and needs additional extract, transform, and load (ETL) processes to make it accessible or to integrate it with structured data for analysis. Amazon Redshift powers the modern data architecture, which enables you to query data across your data warehouse, data lake, and operational databases to gain faster and deeper insights not possible otherwise. With a modern data architecture, you can store data in semi-structured format in your Amazon Simple Storage Service (Amazon S3) data lake and integrate it with structured data on Amazon Redshift. This allows you to make this data available to other analytics and machine learning applications rather than locking it in a silo.

In this post, we discuss the UNLOAD feature in Amazon Redshift and how to export data from an Amazon Redshift cluster to JSON files on an Amazon S3 data lake.

JSON support features in Amazon Redshift

Amazon Redshift features such as COPY, UNLOAD, and Amazon Redshift Spectrum enable you to move and query data between your data warehouse and data lake.

With the UNLOAD command, you can export a query result set in text, JSON, or Apache Parquet file format to Amazon S3. UNLOAD command is also recommended when you need to retrieve large result sets from your data warehouse. Since UNLOAD processes and exports data in parallel from Amazon Redshift’s compute nodes to Amazon S3, this reduces the network overhead and thus time in reading large number of rows. When using the JSON option with UNLOAD, Amazon Redshift unloads to a JSON file with each line containing a JSON object, representing a full record in the query result. In the JSON file, Amazon Redshift types are unloaded as the closest JSON representation. For example, Boolean values are unloaded as true or false, NULL values are unloaded as null, and timestamp values are unloaded as strings. If a default JSON representation doesn’t suit a particular use case, you can modify it by casting to the desired type in the SELECT query of the UNLOAD statement.

Additionally, to create a valid JSON object, the name of each column in the query result must be unique. If the column names in the query result aren’t unique, the JSON UNLOAD process fails. To avoid this, we recommend using proper column aliases so that each column in the query result remains unique while getting unloaded. We illustrate this behavior later in this post.

With the Amazon Redshift SUPER data type, you can store data in JSON format on local Amazon Redshift tables. This way, you can process the data without any network overhead and use Amazon Redshift schema properties to optimally save and query semi structured data locally. In addition to achieving low latency, you can also use the SUPER data type when your query requires strong consistency, predictable query performance, complex query support, and ease of use with evolving schemas and schemaless data. Amazon Redshift supports writing nested JSON when the query result contains SUPER columns.

Updating and maintaining data with constantly evolving schemas can be challenging and adds extra ETL steps to the analytics pipeline. The JSON file format provides support for schema definition, is lightweight, and is widely used as a data transfer mechanism by different services, tools, and technologies.

Amazon OpenSearch Service (successor to Amazon Elasticsearch Service) is a distributed, open-source search and analytics suite used for a broad set of use cases like real-time application monitoring, log analytics, and website search. It uses JSON as the supported file format for data ingestion. The ability to unload data natively in JSON format from Amazon Redshift into the Amazon S3 data lake reduces complexity and additional data processing steps if that data needs to be ingested into Amazon OpenSearch Service for further analysis.

This is one example of how seamless data movement can help you build an integrated data platform with a data lake on Amazon S3, data warehouse on Amazon Redshift and search and log analytics using Amazon OpenSearch Service and any other JSON-oriented downstream analytics solution. For more information about the Lake House approach, see Build a Lake House Architecture on AWS.

Examples of Amazon Redshift JSON UNLOAD

In this post, we show you the following different scenarios:

  • Example 1 – Unload customer data in JSON format into Amazon S3, partitioning output files into partition folders, following the Apache Hive convention, with customer birth month as the partition key. We make a few changes to the columns in the SELECT statement of the UNLOAD command:
    • Convert the c_preferred_cust_flag column from character to Boolean
    • Remove leading and trailing spaces from the c_first_name, c_last_name, and c_email_address columns using the Amazon Redshift built-in function btrim
  • Example 2 – Unload line item data (with SUPER column) in JSON format into Amazon S3 with data not partitioned
  • Example 3 – Unload line item data (With SUPER column) in JSON format into Amazon S3, partitioning output files into partition folders, following the Apache Hive convention, with customer key as the partition key

For the first example, we used the customer table and data from the TPCDS dataset. For examples involving table with SUPER column, we used the customer_orders_lineitem table and data from the following tutorial.

Example 1: Export customer data

For this example, we used the customer table and data from TPCDS dataset. We created the database schema and customer table, and copied data into it. See the following code:

-- Created a new database
create schema json_unload_demo; 

-- created and populated customer table in the new schema

create table json_unload_demo.customer
(
  c_customer_sk int4 not null ,                 
  c_customer_id char(16) not null ,             
  c_current_cdemo_sk int4 ,   
  c_current_hdemo_sk int4 ,   
  c_current_addr_sk int4 ,    
  c_first_shipto_date_sk int4 ,                 
  c_first_sales_date_sk int4 ,
  c_salutation char(10) ,     
  c_first_name char(20) ,     
  c_last_name char(30) ,      
  c_preferred_cust_flag char(1) ,               
  c_birth_day int4 ,          
  c_birth_month int4 ,        
  c_birth_year int4 ,         
  c_birth_country varchar(20) ,                 
  c_login char(13) ,          
  c_email_address char(50) ,  
  c_last_review_date_sk int4 ,
  primary key (c_customer_sk)
) distkey(c_customer_sk);

copy json_unload_demo.customer from 's3://redshift-downloads/TPC-DS/2.13/3TB/customer/' 
iam_role '<<AWS IAM role attached to your amazon redshift cluster>>' 
gzip delimiter '|' EMPTYASNULL;

You can create a default AWS Identity and Access Management (IAM) role for your Amazon Redshift cluster to copy from and unload to your Amazon S3 location. For more information, see Use the default IAM role in Amazon Redshift to simplify accessing other AWS services.

In this example, we unloaded customer data for all customers with birth year 1992 in JSON format into Amazon S3 without any partitions. We make the following changes to the UNLOAD statement:

  • Convert the c_preferred_cust_flag column from character to Boolean
  • Remove leading and trailing spaces from the c_first_name, c_last_name, and c_email_address columns using the btrim function
  • Set the maximum size of exported files in Amazon S3 to 64 MB

See the following code:

unload ('SELECT c_customer_sk,
    c_customer_id ,
    c_current_cdemo_sk ,
    c_current_hdemo_sk ,
    c_current_addr_sk ,
    c_first_shipto_date_sk ,
    c_first_sales_date_sk ,
    c_salutation ,
    btrim(c_first_name),
    btrim(c_last_name),
    c_birth_day ,
    c_birth_month ,
    c_birth_year ,
    c_birth_country ,
    c_last_review_date_sk,
    DECODE(c_preferred_cust_flag, ''Y'', TRUE, ''N'', FALSE)::boolean as c_preferred_cust_flag_bool,
    c_login, 
    btrim(c_email_address) 
    from customer where c_birth_year = 1992;')
to 's3://<<Your Amazon S3 Bucket>>/non-partitioned/non-super/customer/' 
FORMAT JSON 
partition by (c_birth_month)  include
iam_role '<<AWS IAM role attached to your amazon redshift cluster>>'
MAXFILESIZE 64 MB;

When we ran the UNLOAD command, we encountered an error because the columns that used the btrim function all attempted to be exported as btrim (which is the default behavior of Amazon Redshift when the same function is applied to multiple columns that are selected together). To avoid this error, we need to use a unique column alias for each column where the btrim function was used.

If we select the c_first_name, c_last_name, and c_email_address columns by applying the btrim function and c_preferred_cust_flag, we can convert them from character to Boolean.

We ran the following query in Amazon Redshift Query Editor v2:

SELECT btrim(c_first_name) ,
    btrim(c_last_name),
    btrim(c_email_address) , 
    DECODE(c_preferred_cust_flag, 'Y', TRUE, 'N', FALSE)::boolean c_preferred_cust_flag_bool  
    from customer where c_birth_year = 1992 limit 10; 

All three columns that used the btrim function are set as btrim in the output result instead of their respective column name.

An error occurred in UNLOAD because we didn’t use a column alias.

We added column aliases in the following code:

unload ('SELECT c_customer_sk,
    c_customer_id ,
    c_current_cdemo_sk ,
    c_current_hdemo_sk ,
    c_current_addr_sk ,
    c_first_shipto_date_sk ,
    c_first_sales_date_sk ,
    c_salutation ,
    btrim(c_first_name) as c_first_name,
    btrim(c_last_name) as c_last_name,
    c_birth_day ,
    c_birth_month ,
    c_birth_year ,
    c_birth_country ,
    c_last_review_date_sk,
    DECODE(c_preferred_cust_flag, ''Y'', TRUE, ''N'', FALSE)::boolean as c_preferred_cust_flag_bool,
    c_login, 
    btrim(c_email_address) as c_email_addr_trimmed 
    from customer where c_birth_year = 1992;')
to 's3://<<Your Amazon S3 Bucket>>/non-partitioned/non-super/customer/' 
FORMAT JSON 
partition by (c_birth_month)  include
iam_role '<<AWS IAM role attached to your amazon redshift cluster>>'
MAXFILESIZE 64 MB;

After we added column aliases, the UNLOAD command completed successfully and files were exported to the desired location in Amazon S3.

The following screenshot shows data is unloaded in JSON format partitioning output files into partition folders, following the Apache Hive convention, with customer birth month as the partition key into Amazon S3 from the Amazon Redshift customer table.

A query with Amazon S3 Select shows a snippet of data in the JSON file on Amazon S3 that was unloaded.

The column aliases c_first_name, c_last_name, and c_email_addr_trimmed were written into the JSON record as per the SELECT query. Boolean values were saved in c_preferred_cust_flag_bool as well.

Examples 2 and 3: Using the SUPER column

For the next two examples, we used the customer_orders_lineitem table and data. We created the customer_orders_lineitem table and copied data into it with the following code:

-- Created a new table with SUPER column

CREATE TABLE JSON_unload_demo.customer_orders_lineitem
(c_custkey bigint
,c_name varchar
,c_address varchar
,c_nationkey smallint
,c_phone varchar
,c_acctbal decimal(12,2)
,c_mktsegment varchar
,c_comment varchar
,c_orders super
);

-- Loaded data into the new table
COPY json_unload_demo.customer_orders_lineitem 
FROM 's3://redshift-downloads/semistructured/tpch-nested/data/json/customer_orders_lineitem'
IAM_ROLE '<<AWS IAM role attached to your amazon redshift cluster>>'
FORMAT JSON 'auto';

Next, we ran a few queries to explore the customer_orders_lineitem table’s data:

select * from json_unload_demo.customer_orders_lineitem;

select c_orders from json_unload_demo.customer_orders_lineitem;

SELECT attr as attribute_name, val as object_value FROM json_unload_demo.customer_orders_lineitem c, c.c_orders o, UNPIVOT o AS val AT attr;

Example 2: Without partitions

In this example, we unloaded all the rows of the customer_orders_lineitem table in JSON format into Amazon S3 without any partitions:

unload ('select * from json_unload_demo.customer_orders_lineitem;')
to 's3://<<Your Amazon S3 Bucket>>/non-partitioned/super/customer-order-lineitem/'
FORMAT JSON
iam_role '<<AWS IAM role attached to your amazon redshift cluster>>';

After we run the UNLOAD command, the data is available in the desired Amazon S3 location. The following screenshot shows data is unloaded in JSON format without any partitions into Amazon S3 from the Amazon Redshift customer_orders_lineitem table.

A query with Amazon S3 Select shows a snippet of data in the JSON file on Amazon S3 that was unloaded.

Example 3: With partitions

In this example, we unloaded all the rows of the customer_orders_lineitem table in JSON format partitioning output files into partition folders, following the Apache Hive convention, with customer key as the partition key into Amazon S3:

unload ('select * from json_unload_demo.customer_orders_lineitem;')
to 's3://<<Your Amazon S3 Bucket>>/partitioned/super/customer-order-lineitem-1/'
FORMAT JSON
partition by (c_custkey) include
iam_role '<<AWS IAM role attached to your amazon redshift cluster>>';

After we run the UNLOAD command, the data is available in the desired Amazon S3 location. The following screenshot shows data is unloaded in JSON format partitioning output files into partition folders, following the Apache Hive convention, with customer key as the partition key into Amazon S3 from the Amazon Redshift customer_orders_lineitem table.

A query with Amazon S3 Select shows a snippet of data in the JSON file on Amazon S3 that got unloaded.

Conclusion

In this post, we showed how you can use the Amazon Redshift UNLOAD command to unload the result of a query to one or more JSON files into your Amazon S3 location. We also showed how you can partition the data using your choice of partition key while you unload the data. You can use this feature to export data to JSON files into Amazon S3 from your Amazon Redshift cluster or your Amazon Redshift Serverless endpoint to make your data processing simpler and build an integrated data analytics platform.


About the Authors

Dipankar Kushari is a Senior Analytics Solutions Architect with AWS.

Sayali Jojan is a Senior Analytics Solutions Architect with AWS. She has 7 years of experience working with customers to design and build solutions on the AWS Cloud, with a focus on data and analytics.

Cody Cunningham is a Software Development Engineer with AWS, working on data ingestion for Amazon Redshift.
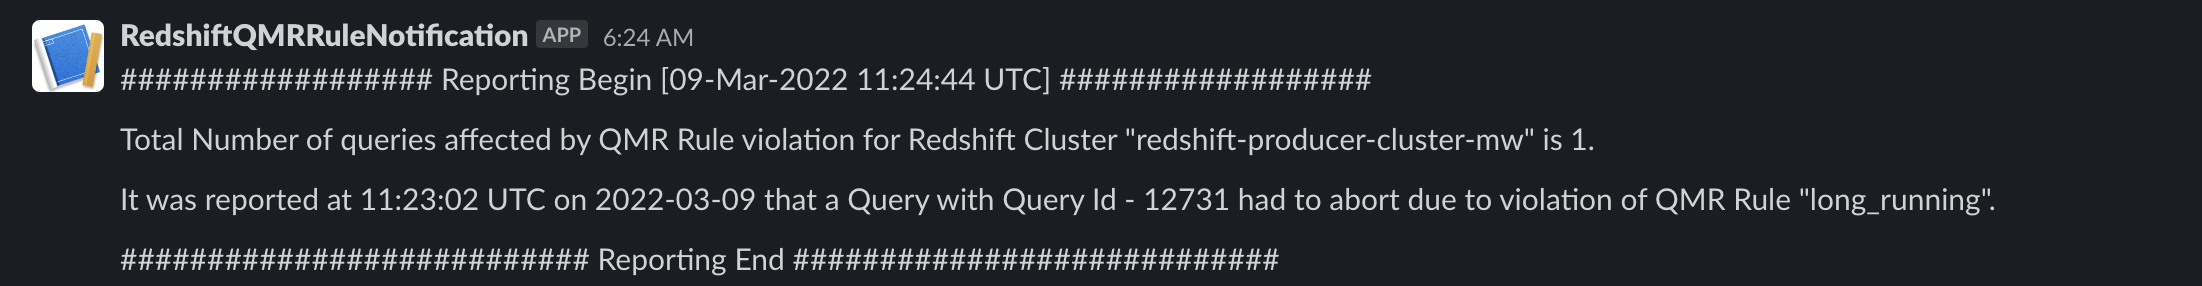
Amazon Redshift at AWS re:Invent 2021 recap

Post Syndicated from Sunaina Abdul Salah original https://aws.amazon.com/blogs/big-data/amazon-redshift-at-aws-reinvent-2021-recap/

The annual AWS re:Invent learning conference is an exciting time full of new product and program launches. At the first re:Invent conference in 2012, AWS announced Amazon Redshift. Since then, tens of thousands of customers have started using Amazon Redshift as their preferred cloud data warehouse. At re:Invent 2021, AWS announced several new Amazon Redshift features that bring easy analytics for everyone while continuing to increase performance and help you break through data silos to analyze all the data in your data warehouse. With re:Invent packed with information and new announcements, it’s easy to miss the best of the updates in Amazon Redshift. In this post, we summarize these announcements, along with resources for you to get more details.

AWS takes analytics serverless

Adam Selipsky took the re:Invent keynote stage on November 29, 2021, for the first time as AWS CEO, announcing a string of innovations along the theme of pathfinders. He shared the story about Florence Nightingale, a pathfinder and data geek who had a passion for statistics, who collected and analyzed data on sanitation impact on mortality rates to mobilize the army at the time to approve new hygiene standards and restructure health efforts. The theme set the stage for the AWS modern data strategy, which enables everyone in the organization to find patterns in data and mobilize their business with data with the right tools for the right job. Selipsky’s announcement of serverless options for four AWS Analytics services, including Amazon Redshift, emphasized the growing need to be able to run complex analytics without touching infrastructure or managing capacity for your applications. Watch Adam Selipsky’s keynote announcement of AWS Analytics services with new serverless options (00:52).

Amazon Redshift: Under the hood

This year, VP of AWS Machine Learning Services Swami Sivasubramanian expanded his keynote to include the entire data and machine learning (ML) journey for all workloads and data types. In addition to mentioning the new serverless option announcement for Amazon Redshift in preview, he dove under the hood of Amazon Redshift to explore core innovations since its inception in 2012 that drove the service to become a best-in-class, petabyte-scale data warehouse for tens of thousands of customers. Sivasubramanian touched on features that enable Amazon Redshift to power large workloads with top-notch performance, including RA3 instances, AQUA (Advanced Query Accelerator), materialized views, short query acceleration, and automatic workload management. He also elaborated on how Amazon Redshift ML uses SQL to make ML predictions from your data warehouse. Neeraja Rentachintala then took you through a demo set in a gaming environment to outline the value of Amazon Redshift Serverless and Amazon QuickSight Q.

Reinvent your business for the future with AWS Analytics

Rahul Pathak, VP of AWS Analytics Services, talked in detail about how you can put your data to work and transform your businesses through end-to-end AWS Analytics services that help you modernize, unify, and innovate. He talked about how customers like Zynga, Schneider Electric, Magellan Rx, Jobcase, and Nasdaq are benefitting from Amazon Redshift with innovations in performance as data volumes grow. He elaborated on how Amazon Redshift helps you analyze all your data with AWS service integration, and touched upon the quest to make analytics easy for everyone with the introduction of the new Query Editor v2, Amazon Redshift Serverless, and data sharing capabilities. Watch the session to gain a deeper understanding of AWS Analytics services.

What’s new with Amazon Redshift, featuring Schneider Electric

This session is a must-watch for every existing and new Amazon Redshift customer to get a full understanding of the breadth and depth of features that Amazon Redshift offers along the dimensions of easy analytics for everyone, analyze all your data, and performance at scale. Eugene Kawamoto, Director of Amazon Redshift Product, goes into detail about all the new launches in 2021, tracing the architectural evolution of Amazon Redshift to the new serverless option. He explores how Amazon Redshift integrates with other popular AWS services to help you break through data silos, analyze all your data, and derive value from this data.

Democratizing data for self-service analytics and ML

Access to all your data for fast analytics at scale is foundational for 360-degree projects involving data engineers, database developers, data analysts, data scientists, business intelligence professionals, and the line of business. In this session, Greg Khairallah and Shruti Worlikar, leaders in the AWS Analytics GTM organization, team up with our customer Jobcase, represented by Senior Scientist Clay Martin, to show how easy-to-use ML can help your organization imagine new products or services, transform your customer experiences, streamline your business operations, and improve your decision-making. A secure, integrated platform that’s easy to use and supports nonproprietary data formats can improve collaboration through data sharing and also improve customer responsiveness.

Introducing Amazon Redshift Serverless

Following the announcements in the keynotes, this session takes you through the new serverless option on Amazon Redshift, which enables you to get started in seconds and run data warehousing and analytics workloads at scale without worrying about data warehouse management. In this session, learn from Yan Leshinsky, VP of Amazon Redshift, and Neeraja Rentachintala, Principal Product Manager for Amazon Redshift, on how Amazon Redshift Serverless automatically provisions data warehouse capacity and intelligently scales the underlying resources to deliver consistently high performance and simplified operations for even the most demanding and volatile workloads.
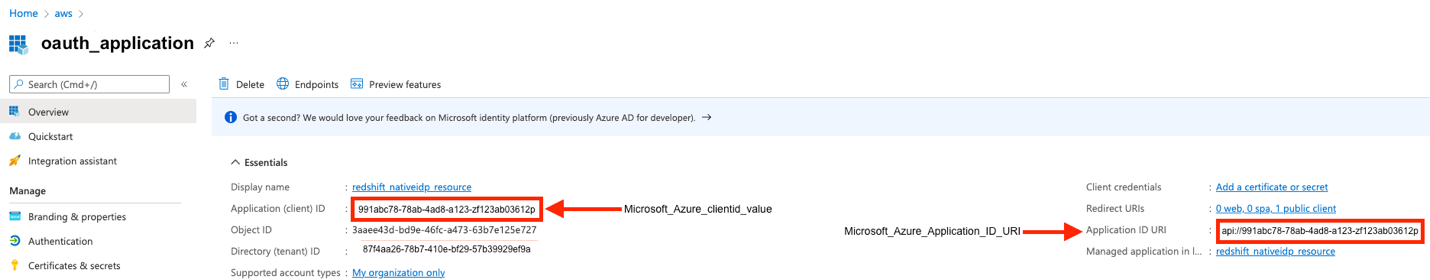
Introduction to AWS Data Exchange for Amazon Redshift

We’ve talked about Amazon Redshift Serverless several times, but there were some exciting announcements from the service leading into re:Invent. We launched AWS Data Exchange for Amazon Redshift, which allows you to combine third-party data found on AWS Data Exchange with your own data from your Amazon Redshift cloud data warehouse, requiring no ETL and accelerating time to value. This provides a powerful enhancement to the strong data-sharing capabilities in Amazon Redshift to share secure, live data across Regions, accounts, and organizations. In this session, product managers Neeraja Rentachintala and Ryan Waldorf walk through the value of this integration and how to access and analyze a provider’s data with data providers, which enables licensing this access to their Amazon Redshift cloud data warehouses. Alex Bohl, Director of Data Innovation from Mathematica, joins them in this session to provide a real-world example.
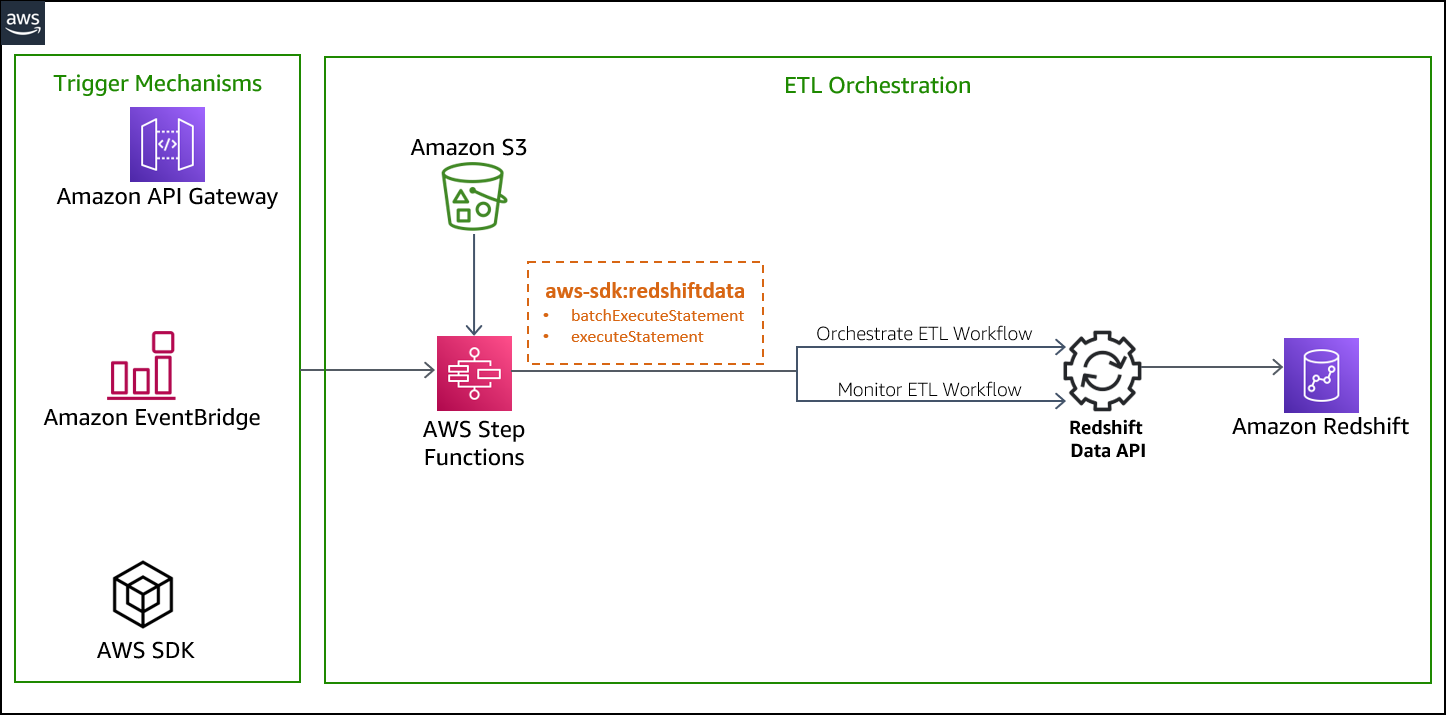
Additional sessions

In addition to these sessions, the hands-on-workshops and chalk talks were packed with customers looking to learn more about Amazon Redshift’s capabilities in ML with Redshift ML, concurrency scaling, and much more. These sessions were not recorded.

Get started with Amazon Redshift

Learn more about the latest and greatest of what Amazon Redshift offers you, and explore the following resources for more information about new releases:


About the Author

Sunaina Abdul Salah leads product marketing for Amazon Redshift.