Tag Archives: announcements

Many voices, one community: Three themes from RSA Conference 2025

Post Syndicated from Anne Grahn original https://aws.amazon.com/blogs/security/many-voices-one-community-three-themes-from-rsa-conference-2025/

RSA Conference (RSAC) 2025 drew 730 speakers, 650 exhibitors, and 44,000 attendees from across the globe to the Moscone Center in San Francisco, California from April 28 through May 1.

The keynote lineup was eclectic, with 37 presentations featuring speakers ranging from NBA Hall of Famer Earvin “Magic” Johnson to public and private-sector luminaries such as former US National Cyber Director Chris Inglis, U.S. Secretary of Homeland Security Kristi Noem, and cryptography experts Tal Rabin, Whitfield Diffie, and Adi Shamir.

Topics aligned with this year’s conference theme, “Many Voices. One Community,” and focused on the security industry’s shared drive to foresee risks, counter threats, and embrace new challenges.

Three themes caught our attention: agentic AI, cryptography, and public-private collaboration.

Agentic AI

The potential of agentic AI to augment human decision-making was a common thread among conversations at the conference. Numerous sessions touched on the topic, and the desire of attendees to understand the technology and learn how to balance its risks and opportunities was clear.

Separating hype from reality

An AI agent is a software program that can interact with its environment (as detailed in Figure 1), collect data, and use the data to perform self-determined tasks to meet predetermined goals.

Figure 1: Generative AI agents

Figure 1: Generative AI agents

Agentic systems offer a fundamentally different approach compared to traditional software, particularly in their ability to handle complex, dynamic, and domain-specific challenges. While traditional systems rely on rule-based automation and structured data, agentic systems use large language models (LLMs)—a subset of generative AI—to operate autonomously. Agents can learn from interactions with users, and make nuanced, context-aware decisions while keeping human analysts in the loop.

Numerous RSAC speakers alluded to AI agents as the next frontier in enterprise transformation. Gartner® predicts that: “By 2028, 33% of enterprise software applications will include agentic AI, up from less than 1% in 2024,” and “at least 15% of day-to-day work decisions will be made autonomously through agentic AI, up from zero percent in 2024.”

However, as organizations build AI agents, understanding the concerns that come with them is critical.

“Agentic AI presents tremendous opportunities to deliver business value and innovative security outcomes. Production deployments require a balance between its capabilities, and robust security and trust mechanisms.”
—Hart Rossman, Global Services Security Vice President at AWS

In the RSAC keynote session The Five Most Dangerous New Attack Techniques…and What to Do for Each, Rob Lee, Chief of Research and Head of Faculty at SANS Institute noted that while security teams are embracing AI to amplify productivity, threat actors are doing the same. He pointed to MIT research that shows adversarial agent systems executing attack sequences are 47 times faster than human operators, with a 93 percent success rate in privilege escalation paths.

Safeguarding GenAI & Agentic Apps, Top 10 Risks in 2025, a half-day Open Worldwide Application Security Project (OWASP) event, focused on helping attendees distinguish real threats from hype. OWASP Gen AI Security Project team members and industry experts reviewed the 2025 OWASP Top 10 List for LLM and GenAI (shown in Figure 2), and introduced Agentic AI—Threats and Mitigations—the first in a series of guides from the OWASP Agentic Security Initiative (ASI) to provide a threat-model-based reference of emerging agentic threats and mitigations. Content feedback can be submitted to ASI in advance of the guide’s next release.

Figure 2: 2025 OWASP Top 10 for LLM Applications

Figure 2: 2025 OWASP Top 10 for LLM Applications

Agentic AI wins Cybersecurity Startup Accelerator

The second annual AWS and CrowdStrike Cybersecurity Startup Accelerator, in collaboration with the NVIDIA Inception program, took place during RSAC. A panel of judges—including George Kurtz, Founder and CEO of CrowdStrike, CJ Moses, Chief Information Security Officer at Amazon, and David Reber Jr., Chief Security Officer at NVIDIA—evaluated startups on innovation, market relevance, and go-to-market potential. Terra Security, a provider of agentic AI-powered, continuous web application penetration testing, was selected from a group of 10 finalists who pitched live. Two runners-up, Kenzo Security and Rig Security, were also recognized for their standout approaches to agentic AI-driven security.

Addressing AI risks

The need to consider your security posture when assessing overall AI readiness was emphasized throughout the conference. A defense-in-depth architecture can help mitigate risks with multiple layers of protection across both traditional and AI software components. Innovative solutions such as AI red teaming, AI behavioral sandboxing, and advanced tracing and evaluation of generative AI agents can enhance your security strategy with a proactive approach to securing AI.

Visit the following resources to help design, build, and operate AI systems: DevsecOps Revolution: Unleashing Generative AI for Automated Excellence, AWS generative AI security, responsible AI, and the Amazon AGI Labs Blog.

Cryptography

Encryption was another key topic. The FIDO Alliance hosted a half-day seminar that focused on developments in the global movement to passwordless technology such as passkeys—cryptographic keys designed to replace passwords by combining the power of public key cryptography with biometric authentication.

In Dude, Where’s My Password? The Challenges of Getting to Passwordless, Andy Ozment, Chief Technology Risk Officer and Executive Vice President at Capital One noted that 88 percent of data compromised in basic web application attacks reported in 2024 involved stolen credentials. Ozment pointed out that “going passwordless” through a combination of X.509 device certificates and FIDO2 passkeys presented Capital One with an opportunity to nearly eliminate entire classes of threats (as detailed in Figure 3), while increasing the quality of user experience.

Figure 3: Using passkeys to reduce risk while advancing user experience

Figure 3: Using passkeys to reduce risk while advancing user experience

Along the way, Ozment said, Capital One’s journey to passwordless was enabled by its transition from on-premises technology to going “all-in” on the public cloud. Watch the recording of his session or view the slides to learn more.

Post-quantum encryption

The state of post-quantum encryption was detailed in the popular Cryptographer’s Panel, moderated by Tal Rabin, Senior Principal Applied Scientist at AWS.

Panelist Vinod Vaikuntanathan, Professor at MIT underscored the impact of the quantum-resistant algorithm standardization process (Figure 4) started by the National Institute of Standards and Technology (NIST) in 2016. “We now have two public key encryption algorithms, and three new digital signature algorithms that are standardized,” he pointed out.

Figure 4: Post-quantum encryption algorithms

Figure 4: Post-quantum encryption algorithms

The panelists agreed that even though quantum computers aren’t here yet, the time to deploy these algorithms is now. NIST recommends phasing out existing encryption methods by 2030 in its Transition to Post-Quantum Cryptography Standards report. However, Vaikuntanathan and Adi Shamir, the “s” in the Rivest–Shamir–Adleman (RSA) public-key cryptosystem, advise organizations to take a hybrid approach that combines classic encryption algorithms such as RSA or Elliptic-curve Diffie–Hellman (ECDH) with post-quantum algorithms such as Module-Lattice-based Key Encapsulation Mechanism (ML-KEM). This approach, which is used by AWS and recommended by The European Commission, offers protection against both current and future threats.

RSAC Award for Excellence in the Field of Mathematics

Dr. Shai Halevi, Senior Principal Applied Scientist at AWS, was presented with the Award for Excellence in the Field of Mathematics for remarkable contributions to many areas of cryptography, including fundamental theory, advanced cryptographic primitives, secure multi-party computations, homomorphic encryption, and cryptographic code obfuscation.

Figure 5: Dr. Shai Halevi receives RSAC award for Excellence in the Field of Mathematics

Figure 5: Dr. Shai Halevi receives RSAC Award for Excellence in the Field of Mathematics

End-to-end encryption

Concerns about the recent US government group chat leak were also raised during the discussion. Public-key cryptography pioneer Whitfield Diffie noted that the use of an encrypted consumer messaging app to communicate classified information broke archiving laws. Because some commercial tools use 256-bit Advanced Encryption Standard (AES) encryption, which is “good enough” to protect communications, he predicted an increase in the use of consumer applications to protect sensitive information in unapproved ways.

The Cybersecurity and Infrastructure Security Agency (CISA) and the Federal Bureau of Investigation (FBI) recently advised individuals and organizations to start using encrypted messaging apps. However, as the role of these applications in business communication expands, it’s important not to lose sight of recordkeeping and compliance obligations. Organizations should consider solutions that offer administrative controls and data retention capabilities along with encryption.

AWS Wickr, for example, is a messaging and collaboration service that protects messaging, calling, file sharing, screen sharing, and location sharing with 256-bit end-to-end encryption. The data retention and administrative controls that it provides help customers meet regulatory requirements and manage user and device data remotely.

Wickr is Department of Defense Cloud Computing Security Requirements Guide Impact Level 5 (DoD CC SRG IL5) and Federal Risk and Authorization Management Program (FedRAMP) High authorized in the AWS GovCloud (US-West) Region. It also meets compliance programs and standards such as Health Insurance Portability and Accountability Act (HIPAA) eligibility, International Organization for Standardization (ISO) 27001, and System and Organization Controls (SOC) 1, 2, and 3.

Visit the AWS News Blog and the AWS Security Blog to learn about AWS passkey multi-factor authentication, how AWS is migrating to post quantum cryptography (PQC), and how we can help you implement a layered encryption strategy for your organization.

Public-private collaboration

Numerous sessions underlined the importance of collaboration to strengthening security. In his keynote, Johnson called attention to a lesson he learned on the basketball court—his peers made him stronger. “Larry Bird made me a better basketball player,” he said, relating his experience to the need for security teams to assist and learn from each other.

In Making America Safe Again Through Cyber Defense, Kristi Noem, U.S. Secretary of Homeland Security equated cybersecurity with national security, and insisted that building on public-private partnerships is “incredibly important.” “Our goal,” she said, “is to use our maximum effect of cooperation to make sure that we’re going after bad actors.”

After assuring attendees that CISA will continue to be America’s cyber defense agency, she urged congress to reauthorize the Cybersecurity Information Sharing Act of 2015. The law, which is set to expire in September, incentivizes businesses to share threat indicators with the Department of Homeland Security (DHS) and helps make sure that both the federal government and companies can take collaborative steps to address threats.

Panelists at an offsite threat intelligence discussion reiterated the ability of private industry to supplement government security capabilities. Adam Meyers, Senior VP, Counter Adversary Operations at CrowdStrike pointed out that technology companies often have more data and signals than governments. The CrowdStrike Falcon solution, he said, processes over 6 trillion events per day, and 55 million events per second at peak. This volume facilitates the detection of threat patterns that might otherwise go unnoticed.

Similarly, Moses noted that the size and scale of AWS infrastructure gives us unique visibility into internet traffic. Our global network of sensors and associated disruption tools observe over 700 million threat interactions every day, out of which 450 million can be classified as malicious. Internal threat intelligence tools such as MadPot, our sophisticated global honeypot system, produce high-fidelity findings (pieces of relevant information) that can be used to drive proactive intelligence sharing, and reduce investigative workloads.

“We’ll work together in order to be able to put a bow on a case and hand it to the FBI and DOJ, such that they don’t have to expend a great amount of resources in order to go forward and try to figure things out that we already know.” —CJ Moses, Chief Information Security Officer and VP of Security Engineering at Amazon

An example of this is the disruption of the cybercriminal group known as Anonymous Sudan. The group was responsible for tens of thousands of distributed denial-of-service (DDoS) attacks against critical infrastructure, corporate networks, and government agencies. With the help of tools like MadPot, AWS experts were able to identify the hosting provider infrastructure that the group used to launch the DDos attacks, and work with providers to disrupt them. Akamai SIRT, Cloudflare, CrowdStrike, DigitalOcean, Flashpoint, Google, Microsoft, PayPal, SpyCloud, and other private sector entities also assisted law enforcement, leading to the indictment of two Anonymous Sudan leaders.

The value of combined perspectives

RSA Conference 2025 might be over, but the learning continues. Additional highlights that include the west stage keynotes, the Innovation Sandbox, and dozens of insightful sessions on topics such as the changing role of the CISO, women in cyber, and of course—cloud security—are available on demand.

If there’s one key takeaway, it’s a collective sense of transition. As we explore the benefits and risks of emerging AI technologies, encryption strategies, and information sharing, it’s important to remember that we cannot effectively combat threats in isolation. Security is a collective endeavor; only by working together can we adapt to evolving challenges and build cyber resilience.

For more information about cloud security, register to join AWS, Google Cloud, and Microsoft online at the SANS 2025 Cloud Security Exchange on August 21.

Anne Grahn

Anne Grahn

Anne is a Senior Worldwide Security GTM Specialist at AWS, based in Chicago. She has 15 years of experience in the security industry and focuses on effectively communicating cybersecurity risk. She maintains a Certified Information Systems Security Professional (CISSP) certification.

Introducing our newest 2025 AWS Heroes cohort

Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/introducing-our-newest-2025-aws-heroes-cohort/

The AWS community is a vibrant network of innovators, problem-solvers, and thought leaders who drive cloud technology forward. Today, we’re excited to shine a spotlight on three exceptional individuals who embody the spirit of innovation, knowledge-sharing, and community building. From architecting scalable solutions for millions of users to fostering inclusive tech groups, these professionals are making notable contributions within the AWS community. Let’s give them a warm welcome!

Christian Bonzelet – Cologne, Germany

DevTools Hero Christian Bonzelet is an AWS Solutions Architect at Bundesliga and creator of promptz.dev (a specialized prompt library for Amazon Q Developer). He brings over a decade of media and entertainment industry expertise to the AWS community. Since his first AWS project in 2013, architecting a high-scale voting system for a major German television broadcast, Christian has been passionate about AWS, serverless architecture, and AI/ML technologies. He excels at helping teams optimize their AWS implementations and develop business-aligned solutions, particularly when designing highly scalable systems serving millions of users. Known for his collaborative approach to system design and architecture, Christian actively shares his insights and experiences with the AWS community.

David Victoria – Monterrey, Mexico

Community Hero David Victoria is a senior cloud architect at Caylent. He has a Master’s in Cybersecurity and a Computer Science degree, and nine AWS certifications. With over a decade of experience delivering secure, cost-effective, and scalable solutions, David leads the AWS User Group Monterrey and helps organize the AWS Community Day México, creating spaces where thousands of builders connect and grow. His commitment to mentoring the next generation of cloud professionals across Latin America reflects his belief that “your network is your net worth.” Beyond his technical expertise, David is dedicated to fostering meaningful relationships within the AWS community, whether through public speaking, community leadership, or technical consulting.

Nora Schöner – Erlangen, Germany

DevTools Hero Nora Schöner is a senior cloud engineer with diverse industry experience who specializes in cloud architecture and DevOps. Her expertise in site reliability engineering and infrastructure as code helps teams build robust, accessible systems for both developers and stakeholders. Nora has been actively involved with AWS User Groups since 2016, co-organizing the AWS User Group Nuremberg and contributing to the AWS Community DACH Support Association. She founded She ‘n IT Nuremberg to connect women in tech and shares her unique blend of cloud technology expertise and manga art passion through her blog at wolkencode.de.

Learn More

Visit the AWS Heroes website if you’d like to learn more about the AWS Heroes program, or to connect with a Hero near you.

— Taylor

Introducing managed query results for Amazon Athena

Post Syndicated from Guy Bachar original https://aws.amazon.com/blogs/big-data/introducing-managed-query-results-for-amazon-athena/

Amazon Athena makes it simple to analyze data without having to set up and manage data processing infrastructure. However, traditionally, you needed to set up an Amazon Simple Storage Service (Amazon S3) bucket to store query results before they could run queries with Athena. The need arose to make it even simpler to start using Athena, with fewer setup steps.

That’s why we’re thrilled to introduce managed query results, a new Athena feature that automatically stores, secures, and manages the lifecycle of query result data for you at no additional cost. Managed query results simplifies your user experience by removing the need to create or choose an S3 bucket in your account to hold results before you run queries. It helps reduce your monthly cost by shifting temporary storage of query results from your S3 bucket to Athena, and eliminates the need for separate processes to delete query result data from your S3 bucket after it’s no longer needed. Now, Athena offers both service managed, temporary result storage and customer managed Amazon S3 storage options to meet different needs.

What’s more, using managed query results doesn’t require complex changes to applications that read query results from existing Athena interfaces, and increases data security. Access to managed query result data is now associated with AWS Identity and Access Management (IAM) permissions scoped to individual Athena workgroups, instead of S3 buckets. Additionally, you can automatically encrypt result data with AWS Key Management Service (AWS KMS) using AWS owned or customer managed keys.

In this post, we demonstrate how to get started with managed query results and, by removing the undifferentiated effort spent on query result management, how Athena helps you get insights from your data in fewer steps than before.

Solution overview

When you use managed query results, you no longer need to create and choose S3 buckets to store query results, or manage lifecycle rules to make sure the result data is eventually cleaned up. The following are some scenarios where this is beneficial:

  • Financial analysts working in teams analyzing market data, each covering different investment areas or financial instruments, might use different workgroups for different kinds of analyses or projects. Now, analysts don’t need to spend time setting up S3 buckets or worry about cleaning up query results when their work is done.
  • Compliance teams can run audit queries on transaction data for regulatory reporting while making sure only authorized team members can access sensitive query results through IAM permissions. Because query results are cleaned up automatically, the compliance team no longer requires separate processes to delete query result data.
  • Data and analytics and platform automation teams who are responsible for streamlined onboarding of new users and teams no longer need to configure individual S3 buckets and permissions for different users and teams, simplifying their automation code.

The following are some of the key features of managed query results in Athena:

  • It removes the need to choose an S3 bucket location before you run queries.
  • There is no additional cost to store your query results, and query results are automatically deleted after a period of time, reducing management overhead from separate bucket cleanup processes.
  • It’s straightforward to get started: new and preexisting workgroups can be seamlessly configured to use managed query results. You can have a mix of Athena managed and customer managed query results in your AWS account.
  • You can use streamlined IAM permissions with access to read results using GetQueryResults and GetQueryResultsStream tied to individual workgroups.
  • Query results are automatically encrypted with your choice of AWS owned or customer managed KMS keys.

Let’s walk through how to get started with managed query results.

Configure your workgroup

Complete the following steps to configure your workgroup:

  1. On the Athena console, choose Workgroups in the navigation pane.
  2. Choose Create workgroup.

Alternatively, you can select an existing workgroup and choose Edit.

  1. For Query result configuration, select Athena managed.
  2. Navigate to the Athena console. To create a new workgroup, in the Workgroups page select the Create Workgroup button. To edit an existing workgroup, select a workgroup from the list and in the workgroup detail page, select the Edit button. Under Query result configuration section, you will see the option for Athena managed:
  3. For Encrypt query results, choose your preferred encryption method

Query result configuration

Figure 1: Query result configuration

Step 2: Configure Encryption

Choose your preferred encryption method for query results:

    1. Encrypt using an AWS owned key – This is the default option. It indicates that you want query results to be encrypted and decrypted by an AWS owned key.
    2. Encrypt using a customer managed key – Choose this option if you want to encrypt and decrypt query results with your own key. To have Athena use your customer managed key, specify the Athena service in the Principal elements of the key policy. For more information, see Setup an AWS KMS key policy for managed storage. To run queries, the user querying data needs permission to access your key.

Query your data

After you’ve configured your workgroup for managed query results, you can immediately start running queries. Let’s run a sample query against the AWS Cost and Usage Report.

The Athena console banner indicates that our workgroup, demo-workgroup, was updated to use managed query results. Our query ran successfully, and we didn’t need to set up an S3 bucket. To download these results, choose Download results CSV.

Running a query against the Cost and Usage report in the Athena console

Figure 2: Running a query against the Cost and Usage report in the Athena console

You can access these results through the Athena console and using the Athena APIs.

Accessing the query results via the Athena API

Figure 3: Accessing the query results via the Athena API

Conclusion

In this post, we introduced managed query results, a new Athena feature that streamlines the query experience through automated storage of query results, provides automatic cleanup, and limits query result access with IAM permissions. Managed query results reduces operational overhead, empowering both data analysts running interactive queries and teams building complex analytics pipelines to focus on deriving insights rather than managing infrastructure. We demonstrated how to configure workgroups for managed storage and effectively use this feature in query scenarios.

To start using managed query results with Athena, simply configure your workgroups through the Athena console or APIs. For more information, see Managed query results.


About the Authors

Guy Bachar is a Sr. Solutions Architect at AWS. He specializes in assisting capital markets and FinTech customers with their cloud transformation journeys. His expertise encompasses identity management, security, and unified communication.

Sayan Chakraborty is a Sr. Solutions Architect at AWS. He helps large enterprises build secure, scalable, and performant solutions on AWS. With a background in enterprise and technology architecture, he has experience delivering large-scale digital transformation programs across a wide range of industry verticals.
Darshit Thakkar is a Technical Product Manager at AWS and works out of Boston, Massachusetts. He works closely with customers to understand how they use data, and drives product innovations that make data more actionable at scale.

Dynamically routing requests with Amazon API Gateway routing rules

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/dynamically-routing-requests-with-amazon-api-gateway-routing-rules/

Effective API management and routing capabilities are crucial for organizations managing complex application architectures. Whether you’re a technology company rolling out new API versions to millions of users, or a financial services organization conducting A/B tests to optimize customer experiences, the ability to route API traffic dynamically and efficiently is essential.

Today, Amazon API Gateway announces support for dynamic routing rules for custom domain names in all supported AWS Regions. This new capability enables you to route API requests based on HTTP header values, either independently or in combination with URL paths. In this post, you will learn how to use this new capability to implement routing strategies such as API versioning and gradual rollouts without modifying your API endpoints.

Dynamic Routing Rules Overview

Many organizations require dynamic API routing capabilities to support their evolving business needs. As a line-of-business persona, you want to be able to test new user experiences with specific customer segments, while maintaining their existing flows intact. As an engineer, you want to be able to maintain multiple API versions across different client applications while ensuring regulatory compliance. Prior to this launch, developers using API Gateway implemented dynamic routing by using different URL paths, such as “/v1/products” and “/v2/products”.

With this new launch, you can implement dynamic routing logic with a simple declarative configuration within the custom domain name settings. The new routing rule mechanism allows you to make routing decisions based on HTTP headers, base paths, or a combination of both. Developers are no longer required to create new or alter existing paths to smoothly transition between API versions, they can simply specify the desired value in the request HTTP header. Among other possibilities, you can implement cell-based architecture routing, A/B testing, or dynamic backend selection based on hostname, tenant ID, accepted response media type, or cookie value. By implementing routing logic directly within the API Gateway, you can eliminate proxy layers and complex URL structures while maintaining fine-grained control over your API traffic. This new feature seamlessly integrates with existing API Gateway capabilities and supports both public and private REST APIs. The following diagram shows how you can use routing rules for header and base-path based routing. This example uses a single level resource /products to show path matching, however depending on your use-case you could also use multi-level paths like /products/items.

Figure 1. Using routing rules for header and base-path based routing

In the following section you’ll learn how to implement header-based routing, use the new routing rules construct for common scenarios like API versioning and A/B testing, and configure rules with different routing conditions and priorities to achieve the desired behavior.

What is a routing rule

A routing rule is a new resource type uniquely associated with a single custom domain. It represents a collection of conditions that, when matched, cause the incoming request to be forwarded to a specific API and stage. Routing rules have three configuration properties:

  • The Conditions property defines the criteria that must be met for actions to be taken. A rule can include up to two header conditions and one base path condition, and all specified conditions must be met to trigger the action. If no conditions are defined for a rule, it serves as a catch-all rule matching all requests.
  • The Actions property defines what actions will be taken when rule conditions are met. At the time of this launch the supported action is invoking any stage of any REST API within the same account and region boundaries.
  • The Priority property defines the order that rules are evaluated in, with 1 being highest priority and 1,000,000 the lowest. You cannot reuse same priority value for more than one rule. AWS recommends you leave ample space between sequential rules to make it easy to add new rules in future, for example use 100, 200, 300 instead of 1, 2, 3.

Header conditions, specified via a MatchHeaders property, are used to match HTTP request header values, such as x-version=v1. Conforming to RFC 7230, header names are not case sensitive, while header values are. You can also use wildcards in header values for prefix, suffix, and contains match. See the following examples using AWS CloudFormation templates:

Exact match:

- MatchHeaders: 
	AnyOf: 
		- Header: "x-version" 
		ValueGlob: "alpha-v2-latest"

Will only match x-version=alpha-v2-latest

Prefix match:

- MatchHeaders: 
	AnyOf: 
	- Header: "x-version" 
	ValueGlob: "*latest"

Matches x-version=alpha-v2-latest, but not x-version=alpha-v2

Suffix match:

- MatchHeaders: 
	AnyOf: 
		- Header: "x-version" 
		ValueGlob: "alpha*"

Will match x-version=alpha-v2-latest and x-version=alpha-v1, but not x-version=beta-v1

Prefix and suffix match.

- MatchHeaders: 
	AnyOf: 
		- Header: "x-version" 
		ValueGlob: "*v2*"

Matches x-version=alpha-v2-latest and x-version=beta-v2-test, but not x-version=alpha-v1

Base path condition, specified via MatchBasePaths property, is used to match the incoming request path. The matching is case sensitive.

- MatchBasePaths: 
	AnyOf: 
		- "products"

You can have up to two MatchHeaders and one MatchBasePaths conditions per routing rule. Conditions are evaluated using the AND operator, meaning all conditions must be met for the action to be taken. Both condition types support a single comparison value under AnyOf property. The following snippet illustrates a sample routing rule with two MatchHeaders conditions and a single MatchBasePaths condition.

ProductsV1RoutingRule: 
	Type: 'AWS::ApiGatewayV2::RoutingRule' 
	Properties: 
		DomainNameArn: !Sub "arn:aws:apigateway:${AWS::Region}::/domainnames/${ApiCustomDomain}" 
		Priority: 100 
		Conditions: 
			- MatchHeaders: 
				AnyOf: 
					- Header: "x-version" 
					ValueGlob: "v2" 
			- MatchHeaders: 
				AnyOf: 
					- Header: "x-user-cohort" 
					ValueGlob: "beta-testers" 
			- MatchBasePaths: 
				AnyOf: 
					- "products" 
		Actions: 
				- InvokeApi:
					ApiId: !Ref ProductsV2Api 
					Stage: !Ref ProductsV2Stage

This rule matches requests to https://example.com/products when both header conditions are met – x-version=v2 and x-user-cohort=beta-testers. This rule does not match requests to any other base path, such as https://example.com/orders, or requests that do not match at least one header condition.

For scenarios like API versioning, you can create rules that evaluate headers such as “accept” or “version” to route traffic to different API implementations. For example, to route requests containing “x-version: api-beta” to your beta API, you would create a rule specifying this header condition and set the action to route to your beta API deployment.

Header-based routing also simplifies A/B testing by allowing you to define client cohorts based on custom headers, allowing controlled experiments with different configurations. You can create rules that check for a custom header like “x-test-group” to route specific users to different API implementations. The priority system ensures predictable routing behavior – when multiple rules match a request, the rule with the lowest priority number (highest precedence) determines the routing. Combining header and path conditions within a single rule enables complex routing scenarios such as version-specific routing for specific API resources instead of the entire API, as illustrated in the following diagram.

Figure 2. A routing configuration with two header and one path conditions in API Gateway Console.

Review the API Gateway documentation for detailed guide on creating routing rules.

Configuring Routing Mode

Before you begin creating routing rules, you must first create at least one API, stage, and a custom domain name. You can configure your custom domain name with the new routing mode setting.

  • API mappings only. This is the default mode. When using this mode, you can continue to use base path mappings to route requests to different APIs, and not use Routing Rules at all. This mode maintains the current behavior, where requests are routed based on base path mappings only.
  • Routing rules then API mappings. With this mode you can use Routing Rules while continuing to keep base path mappings as a fallback. When you use this mode, the Routing Rules always take precedence, and unmatched requests are evaluated against base path mappings. This mode is useful for gradually transitioning your APIs to Routing Rules.
  • Routing rules only. This mode gives you the flexibility to use routing rules only, and not rely on the base paths that you may have previously created on the domain using API mappings. This is the recommended routing mode; it is helpful when you are starting off with a new custom domain or finished transitioning from API mappings to Routing Rules for an existing custom domain.

When switching from one routing mode to another, always test your new configuration in non-production environments first. For example, when switching mode from API mappings only to routing rules only, your traffic will only be routed with routing rules; existing API mappings will no longer take effect.

Onboarding to Header-Based Routing

You can adopt the new Header-Based Routing for your existing API Gateway custom domains with zero-downtime, risk-minimized approach. The first step is to configure your custom domain to use the Routing rules then API mappings mode using the API Gateway console, AWS CLI, or your infrastructure-as-code (IaC) tool. This configuration ensures that while you gradually create Routing Rules, your existing base path mappings continue to function as fallback routes. Since Routing Rules are evaluated before base path mappings, and in the absence of any matching rules, requests automatically fall back to your existing base path mappings, your current API traffic remains unaffected during this transition.

Once you’ve configured the routing mode, you can progressively introduce Routing Rules alongside your existing setup. For example, you might start by creating a rule with a specific test header that routes to a new API version, allowing you to validate the routing behavior with controlled test traffic while production traffic continues flowing through your existing base path mappings. As you gain confidence in the new routing configuration, you can gradually expand your rules, adjust priorities, and optionally migrate away from base path mappings entirely. This incremental approach, combined with API Gateway’s observability capabilities described in the next section, enables you to validate each change and ensure your API consumers experience no disruption during the transition.

Observability

API Gateway provides comprehensive visibility into how your routing rules are processing requests through access logging. Each request now includes additional context variables that help you understand the routing decision process. The $context.customDomain.routingRuleIdMatched variable identifies which rule was matched and applied to the request, while existing variables like $context.domainName, $context.apiId, and $context.stage provide the complete routing context. By analyzing these access logs, you can verify routing behavior, troubleshoot unexpected routes, and gather insights about traffic patterns across different API versions or test variants.

End-to-end example

Consider a real-world scenario where a team needs to gradually migrate users to a new API version, such as an e-commerce platform updating its checkout API from v1 to v2. First, the team creates two different REST APIs – one for each version. Then, they set up a Routing Rule with priority 100 that checks for the header x-version=v2 and routes matching requests to the v2 API. They also create another rule with priority 200 that routes all requests with paths starting with /checkout to v1 API as a fallback.

Figure 3. Gradually transitioning clients from v1 to v2 API.

In the application code they add the x-version header for a small percentage of users. They monitor the performance and error rates using API Gateway’s telemetry capabilities by tracking the access and execution logs, along with emitted metrics. As their confidence grows, they gradually increase the percentage of users sending the v2 header. This approach ensures a controlled migration with minimal risk and ability to quickly rollback by simply removing the header from requests or changing a routing rule.

Sample

Follow the instructions in this GitHub repository to provision the sample in your AWS account. The project illustrates using dynamic routing with API Gateway.

Conclusion

Header-based routing brings significant advantages to API Gateway users. The feature’s backward compatibility ensures a smooth transition path – you can maintain existing base path mappings while gradually adopting Routing Rules, or use both mechanisms simultaneously with the fallback option. This flexibility allows you to migrate at your own pace without disrupting existing applications. The solution is cost-effective, with no additional charges for using Routing Rules on REST APIs. It reduces requirements to leverage extra service and infrastructure for dynamic routing. The priority-based evaluation system provides deterministic routing behavior, making it easier to understand and troubleshoot routing decisions.

To learn more about API Gateway header-based routing see the service documentation.

To learn more about Serverless architectures see Serverless Land.

AWS Weekly Roundup: Amazon Aurora DSQL, MCP Servers, Amazon FSx, AI on EKS, and more (June 2, 2025)

Post Syndicated from Prasad Rao original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-aurora-dsql-mcp-servers-amazon-fsx-ai-on-eks-and-more-june-2-2025/

It’s AWS Summit Season! AWS Summits are free in-person events that take place across the globe in major cities, bringing cloud expertise to local communities. Each AWS Summit features keynote presentations highlighting the latest innovations, technical sessions, live demos, and interactive workshops led by Amazon Web Services (AWS) experts. Last week, events took place at AWS Summit Tel Aviv and AWS Summit Singapore.

The following photo shows the packed keynote at AWS Summit Tel Aviv.

AWS Summit Tel Aviv Keynote

Find an AWS Summit near you and join thousands of AWS customers and cloud professionals taking the next step in their cloud journey.

Last week, the announcement that piqued my interest most was the general availability of Amazon Aurora DSQL, which was introduced in preview at re:Invent 2024. Aurora DSQL is the fastest serverless distributed SQL database that enables you to build always available applications with virtually unlimited scalability, the highest availability, and zero infrastructure management.

Aurora DSQL active-active distributed architecture is designed for 99.99% single-Region and 99.999% multi-Region availability with no single point of failure and automated failure recovery. This means your applications can continue to read and write with strong consistency, even in the rare case an application is unable to connect to a Region cluster endpoint.

Single and multi region deployment of Amazon Aurora DSQL

What’s more fascinating is the journey behind building Aurora DSQL, a story that goes beyond the technology in the pursuit of engineering efficiency. Read the full story in Dr. Werner Vogels’ blog post, Just make it scale: An Aurora DSQL story.

Last week’s launches
Here are the other launches that got my attention:

  • Announcing new Model Context Protocol (MCP) servers for AWS Serverless and Containers – MCP servers are now available for AWS Lambda, Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), and Finch. With MCP servers, you can get from idea to production faster by giving your AI assistants access to an up-to-date framework on how to correctly interact with your AWS service of choice. To download and try out the open source MCP servers, visit the aws-labs GitHub repository.
  • Announcing the general availability of Amazon FSx for Lustre Intelligent-Tiering – FSx for Lustre Intelligent-Tiering, a new storage class, automatically optimizes costs by tiering cold data to the applicable lower-cost storage tier based on access patterns and includes an optional SSD read cache to improve performance for your most latency-sensitive workloads.
  • Amazon FSx for NetApp ONTAP now supports write-back mode for ONTAP FlexCache volumes – Write-back mode is a new ONTAP capability that helps you achieve faster performance for your write-intensive workloads that are distributed across multiple AWS Regions and on-premises file systems.
  • AWS Network Firewall Adds Support for Multiple VPC Endpoints – AWS Network Firewall now supports configuring up to 50 Amazon Virtual Private Cloud (Amazon VPC) endpoints per Availability Zone for a single firewall. This new capability gives you more options to scale your Network Firewall deployment across multiple VPCs, using a centralized security policy.
  • Cost Optimization Hub now supports Savings Plans and reservations preferences – You can now use Cost Optimization Hub, a feature within the Billing and Cost Management Console, to configure preferred Savings Plans and reservation term and payment options preferences, so you can see your resulting recommendations and savings potential based on your preferred commitments.
  • AWS Neuron introduces NxD Inference GA, new features, and improved tools – With the release of Neuron 2.23, the NxD Inference library (NxDI) moves from beta to general availability and is now recommended for all multi-chip inference use cases. Neuron 2.23 also introduces new training capabilities, including context parallelism and Odds Ratio Preference Optimization (ORPO), and adds support for PyTorch 2.6 and JAX 0.5.3.
  • AWS Pricing Calculator, now generally available, supports discounts and purchase commitment – We announced the general availability of the AWS Pricing Calculator in the AWS console. You can now create more accurate and comprehensive cost estimates by providing two types of cost estimates: cost estimation for a workload, and estimation of a full AWS bill. You can also import your historical usage or create net new usage when creating a cost estimate. Additionally, with the new rate configuration inclusive of both pricing discounts and purchase commitments, you can gain a clearer picture of potential savings and cost optimizations for your cost scenarios.
  • AWS CDK Toolkit Library is now generally available – AWS CDK Toolkit Library provides programmatic access to core AWS CDK functionalities such as synthesis, deployment, and destruction of stacks. You can use this library to integrate CDK operations directly into your applications, custom CLIs, and automation workflows, offering greater flexibility and control over infrastructure management.
  • Announcing Red Hat Enterprise Linux for AWS – Red Hat Enterprise Linux (RHEL) for AWS, starting with RHEL 10, is now generally available, combining Red Hat’s enterprise-grade Linux software with native AWS integration. RHEL for AWS is built to achieve optimum performance of RHEL running on AWS.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Additional updates
Here are some additional projects, blog posts, and news items that you might find interesting:

  • Introducing AI on EKS: powering scalable AI workloads with Amazon EKS – AI on EKS is a new open source initiative from AWS designed to help you deploy, scale, and optimize AI/ML workloads on Amazon EKS. AI on EKS repository includes deployment-ready blueprints for distributed training, LLM inference, generative AI pipelines, multi-model serving, agentic AI, GPU and Neuron-specific benchmarks, and MLOps best practices.
  • Revolutionizing earth observation with geospatial foundation models on AWS – Emerging transformer-based vision models for geospatial data—also called geospatial foundation models (GeoFMs)—offer a new and powerful technology for mapping the earth’s surface at a continental scale. This post explores how Clay Foundation’s Clay foundation model can be deployed for large-scale inference and fine-tuning on Amazon SageMaker. You can use the ready-to-deploy code samples to get started quickly with deploying GeoFMs in your own applications on AWS.

High level solution flow for inference and fine tuning using Geospatial Foundation Models

  • Going beyond AI assistants: Examples from Amazon.com reinventing industries with generative AI – Non-conversational applications offer unique advantages, such as higher latency tolerance, batch processing, and caching, but their autonomous nature requires stronger guardrails and exhaustive quality assurance compared to conversational applications, which benefit from real-time user feedback and supervision. This post examines four diverse Amazon.com examples of non-conversational generative AI applications.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Stockholm (June 4), Sydney (June 4–5), Hamburg (June 5), Washington (June 10–11), Madrid (June 11), Milan (June 18), Shanghai (June 19–20), and Mumbai (June 19).
  • AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Milwaukee, USA (June 5), Mexico (June 14), Nairobi, Kenya (June 14), and Colombia (June 28).

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Prasad

New and improved Amazon Q Developer experience in the AWS Management Console

Post Syndicated from Brendan Jenkins original https://aws.amazon.com/blogs/devops/new-and-improved-amazon-q-developer-experience-in-the-aws-management-console/

Amazon Q Developer just launched a new agentic experience within the AWS Management Console, that enables builders to get deeper insights about their AWS resources and improve their operational troubleshooting efficiency. This expands the agentic capabilities of Amazon Q Developer from both the integrated development environment (IDE) and command line interface (CLI) to the AWS console. Amazon Q Developer now functions as a resource analysis and operational troubleshooting assistant, able to consult multiple information sources and resolve complex queries, to get deeper insight into AWS environments faster and more easily than before. These capabilities are also available in chat applications such as Microsoft Teams and Slack. Now users can ask any question about AWS services and their resources, leaving Amazon Q Developer to automatically identify appropriate tools for the task, selecting from any AWS API across all services. It breaks queries into executable steps, asks for clarification when needed and combines information from multiple services to solve the task at hand. It can help analyze relationships between resources across multiple AWS services, examine configurations spanning different parts of infrastructure, synthesize information from various data sources to provide comprehensive insights, and respond to complex queries with detailed, actionable information.

For example, while troubleshooting an AWS Lambda function, a builder can simply ask, “How is this Lambda function getting invoked?” or “What are the IAM roles and permissions of my Lambda function?” and Amazon Q Developer will provide insights about the dependencies and interdependencies, evaluating their integration with other AWS services – all from a single natural language prompt. This enhancement allows builders to quickly obtain nuanced, contextual information about their AWS environment, significantly reducing the time and effort required for complex infrastructure analysis.

In this blog post, I’ll showcase several examples of complex prompts to demonstrate how Amazon Q Developer now delivers relevant and insightful responses based on the builder’s specific resources. Specifically, we’ll deep-dive into two main use cases: deeper resource introspection analysis and increased operational troubleshooting efficiency.

Deeper resource introspection and analysis

Amazon Q Developer now offers enhanced capabilities that make it even easier for builders to understand their AWS resources. With a single prompt, builders can now get comprehensive insights about their AWS services that previously required multiple steps. For example, when analyzing Amazon Simple Notification Service (SNS) topics and their subscribers, builders can simply ask “Show me all my SNS topics and their subscribers” to get a complete view of their configurations. This streamlined approach saves valuable time and effort, allowing developers to focus on building rather than navigating through multiple queries.

These new enhanced capabilities enable builders to simply ask for the insight needed, and Amazon Q Developer will perform the necessary multi-step reasoning based on a builder’s prompt. When the request is made, Amazon Q Developer determines the analytical steps required, retrieves information about the resources from multiple data sources, analyzes the relationships and configurations, and provides a comprehensive answer that addresses the need. Rather than builders having to think about which APIs to call or which services to check, Amazon Q Developer handles the complexity of the analysis, allowing builders to focus on understanding infrastructure rather than querying it.

To illustrate Amazon Q Developer’s capability in handling complex queries, let’s consider an example. Suppose a builder has a three-tier web application in an AWS account and they need to identify which Amazon Elastic Compute Cloud (Amazon EC2) instances, based on their Amazon Machine Images (AMIs) in the application layer, are actively communicating with Amazon Relational Database (RDS) in the backend. With this new update, a builder could open a new Amazon Q Developer chat in the AWS Management Console, and enter a prompt such as “List the AMIs used by my running EC2 instances in us-west-2 that can communicate with my RDS cluster”.

User prompts Amazon Q Developer about which Amazon EC2 AMIs are being used that communicate with Amazon RDS in the backend

Figure 1: Prompt to Amazon Q Developer and Amazon RDS database

Based on Amazon Q Developer’s response shown in figure 1 above, Amazon Q Developer was able to list the steps it took to gather the information, pulled applicable information from each service API, and gave one comprehensive and detailed insight about which AMIs were being used to communicate with the Amazon RDS cluster. This shows how Amazon Q Developer can take a single prompt, pull in information from multiple resources and give a comprehensive insight.

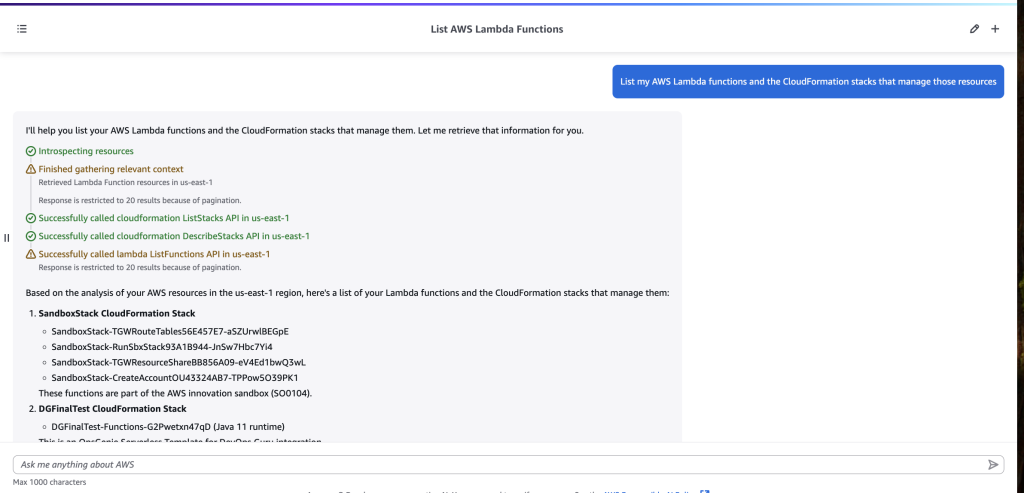
Let’s move to another example around AWS Lambda. Suppose a builder wants to know which AWS CloudFormation stacks are managing Lambda function resources. To do this, a builder could enter a prompt such as “List my AWS Lambda functions and the CloudFormation stacks that manage those resources”.

User prompts Amazon Q Developer to see what AWS CloudFormation Stacks are managing their AWS Lambda resources.

Figure 2: Prompt to Amazon Q Developer about Lambda and AWS CloudFormation

As shown above in figure 2, Amazon Q Developer was able to pull AWS CloudFormation information related to the AWS Lambda resources, and list each stack that was associated with the Lambda functions in the account. This, for example, can help many development and IT professionals better understand and manage their account resources by leveraging the complex reasoning of Amazon Q Developer.

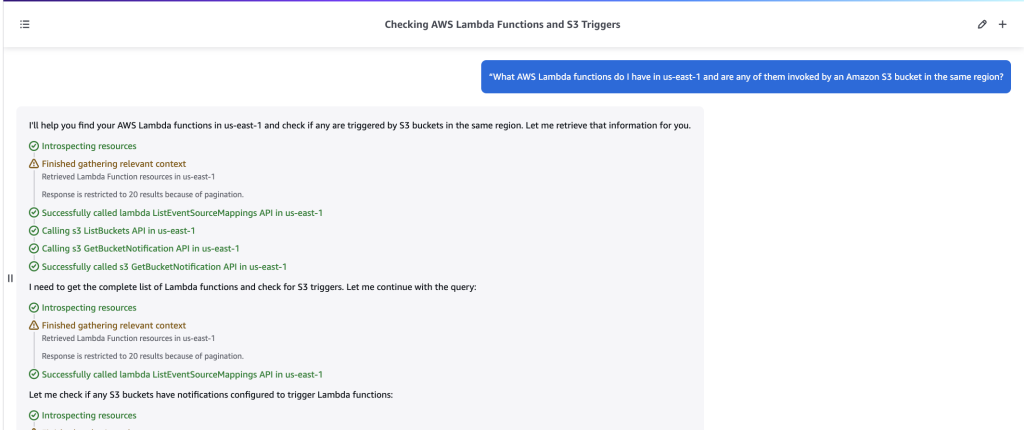
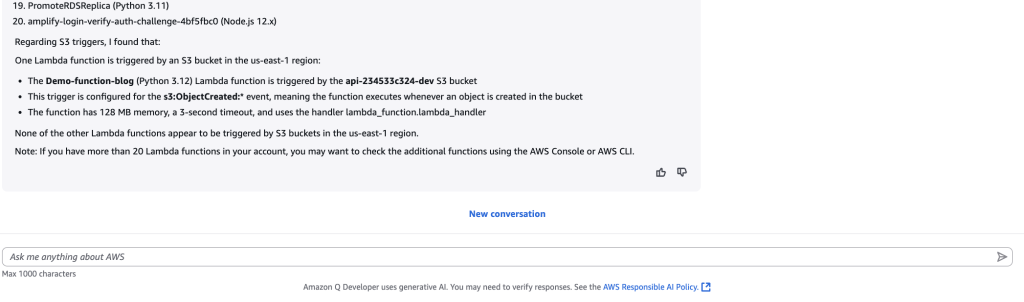
Proceeding with one more example around AWS Lambda, let’s now suppose a builder wants to use Amazon Q Developer to see if there are any Amazon Simple Storage Service (Amazon S3) buckets invoking an AWS Lambda function in their AWS account. To identify this, a builder could enter a prompt such as “What AWS Lambda functions do I have in us-east-1 and are any of them invoked by an Amazon S3 bucket in the same region?”.

User prompts Amazon Q Developer to see if they have any AWS Lambda functions with Amazon S3 buckets as a trigger in their AWS account.User prompts Amazon Q Developer to see if they have any AWS Lambda functions with Amazon S3 buckets as a trigger in their AWS account.

Figure 3: Prompt and response from Amazon Q Developer about Amazon S3 and AWS Lambda

As shown in figure 3 above, Amazon Q Developer again called applicable service APIs to analyze Amazon S3 and AWS Lambda resources and was able to find that there was one AWS Lambda function with S3 as an event trigger.

Furthermore, building on our previous example, builders can try prompts around costs as well. For example, a builder can now prompt Amazon Q Developer “How much did I spend on Lambda functions that are invoked by my S3 bucket?” and Amazon Q will use its deeper resource introspection to tie costs to the resources that are connected.

These examples demonstrate Amazon Q Developer’s enhanced capability to process complex prompts involving multiple resource relationships. This improvement allows builders to obtain comprehensive answers with fewer steps, streamlining the overall process of asking questions about resources in accounts and making it easier to understand and manage AWS resources.

Improved Operational Troubleshooting

Amazon Q Developer can not only discover resources, their configurations, and their relationships, but also correlate that information with logs, metrics, and events to identify, analyze, and determine the root cause while troubleshooting operational issues in the AWS console. This helps streamline the process of resolving issues to enable quick troubleshooting.

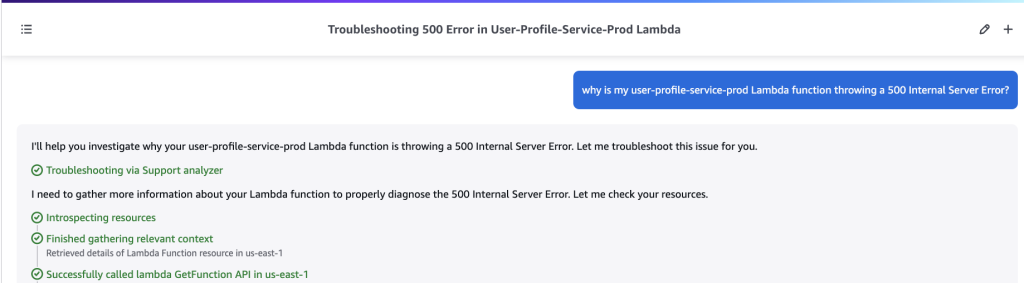
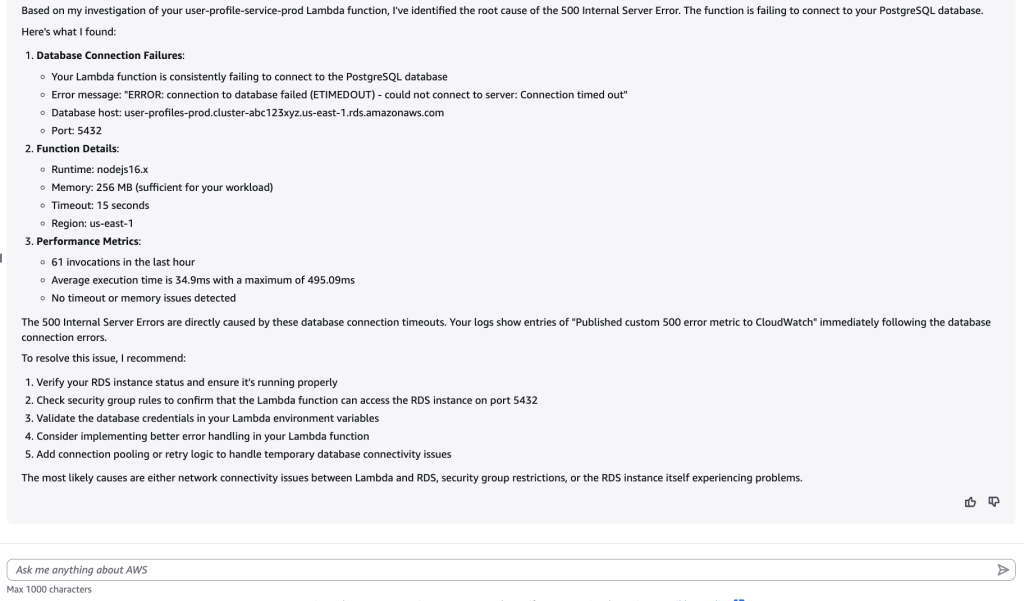
To illustrate Amazon Q Developer’s capability in improved operational troubleshooting, let’s consider an example. Suppose a builder has a simple payment processing application consisting of Amazon API Gateway, AWS Lambda, and Amazon RDS in the backend. Furthermore, the application is returning 500 internal server errors causing downstream issues. Now, a builder can prompt Amazon Q Developer “Why is my user-profile-service-prod Lambda function throwing a 500 Internal server error?”.

User prompts Amazon Q Developer to see why their AWS Lambda functions are facing 500 internal server errors.

Figure 4: Prompt to Amazon Q Developer about internal server error

As shown above in figure 4, Amazon Q Developer automatically begins to gather relevant Amazon CloudWatch metrics, examines the function’s configuration and permissions, checks connected services like API Gateway and Amazon RDS, and analyzes recent changes

Response from Amazon Q after its analysis of various data sources.

Figure 5: Response from Q Developer for database timeouts

As shown above in figure 5, after querying applicable resources, Amazon Q Developer identified the root cause of the 500 internal server error. It shared information it pulled from the database and Lambda function logs and referenced a custom CloudWatch metric dashboard for evidence that the issue is due to database connection timeouts. Lastly, Amazon Q Developer also provided a list of ways to resolve the issue it identified. This example showcases how this new capability streamlines the process of analyzing operational issues, enabling quick troubleshooting.

Conclusion

The examples we’ve shown demonstrate how Amazon Q Developer handles the heavy lifting for users even better than before – from breaking down requests into analytical steps, to gathering data from multiple sources, to delivering meaningful insights about infrastructure, costs, and providing troubleshooting assistance.

As we continue to enhance Amazon Q Developer’s multi-step reasoning capabilities, builders will see it tackle even more complex analysis scenarios, helping them better understand and optimize AWS environments. Whether analyzing security configurations, examining resource relationships, or troubleshooting infrastructure issues, Amazon Q Developer can help save time and provide deeper insights into AWS resources.

To learn more and get started, visit Amazon Q Developer and Chatting with Amazon Q Developer in AWS Console Documentation.

About the authors

Brendan Jenkins

Brendan Jenkins is a Tech Lead Solutions Architect at Amazon Web Services (AWS) working with Enterprise AWS customers providing them with technical guidance and helping achieve their business goals. He has an area of specialization in DevOps and Machine Learning technology.

Amazon FSx for Lustre launches new storage class with the lowest-cost and only fully elastic Lustre file storage

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/amazon-fsx-for-lustre-adds-new-storage-class-with-the-lowest-cost-and-only-fully-elastic-lustre-file-storage/

Seismic imaging is a geophysical technique used to create detailed pictures of the Earth’s subsurface structure. It works by generating seismic waves that travel into the ground, reflect off various rock layers and structures, and return to the surface where they’re detected by sensitive instruments known as geophones or hydrophones. The huge volumes of acquired data often reach petabytes for a single survey and this presents significant storage, processing, and management challenges for researchers and energy companies.

Customers who run these seismic imaging workloads or other high performance computing (HPC) workloads, such as weather forecasting, advanced driver-assistance system (ADAS) training, or genomics analysis, already store the huge volumes of data on either hard disk drive (HDD)-based or a combination of HDD and solid state drive (SSD) file storage on premises. However, as these on premises datasets and workloads scale, customers find it increasingly challenging and expensive due to the need to make upfront capital investments to keep up with performance needs of their workloads and avoid running out of storage capacity.

Today, we’re announcing the general availability of the Amazon FSx for Lustre Intelligent-Tiering, a new storage class that delivers virtually unlimited scalability, the only fully elastic Lustre file storage, and the lowest cost Lustre file storage in the cloud. With a starting price of less than $0.005 per GB-month, FSx for Lustre Intelligent-Tiering offers the lowest cost high-performance file storage in the cloud, reducing storage costs for infrequently accessed data by up to 96 percent compared to other managed Lustre options. Elasticity means you no longer need to provision storage capacity upfront because your file system will grow and shrink as you add or delete data, and you pay only for the amount of data you store.

FSx for Lustre Intelligent-Tiering automatically optimizes costs by tiering cold data to the applicable lower-cost storage tier based on access patterns and includes an optional SSD read cache to improve performance for your most latency sensitive workloads. Intelligent-Tiering delivers high performance whether you’re starting with gigabytes of experimental data or working with large petabyte-scale datasets for your most demanding artificial intelligence/machine learning (AI/ML) and HPC workloads. With the flexibility to adjust your file system’s performance independent of storage, Intelligent-Tiering delivers up to 34 percent better price performance than on premises HDD file systems. The Intelligent-Tiering storage class is optimized for HDD-based or mixed HDD/SSD workloads that have a combination of hot and cold data. You can migrate and run such workloads to FSx for Lustre Intelligent-Tiering without application changes, eliminating storage capacity planning and management, while paying only for the resources that you use.

Prior to this launch, customers used the FSx for Lustre SSD storage class to accelerate ML and HPC workloads that need all-SSD performance and consistent low-latency access to all data. However, many workloads have a combination of hot and cold data and they don’t need all-SSD storage for colder portions of the data. FSx for Lustre is increasingly used in AI/ML workloads to increase graphics processing unit (GPU) utilization, and now it’s even more cost optimized to be one of the options for these workloads.

FSx for Lustre Intelligent-Tiering
Your data moves between three storage tiers (Frequent Access, Infrequent Access, and Archive) with no effort on your part, so you get automatic cost savings with no upfront costs or commitments. The tiering works as follows:

Frequent Access – Data that has been accessed within the last 30 days is stored in this tier.

Infrequent Access – Data that hasn’t been accessed for 30 – 90 days is stored in this tier, at a 44 percent cost reduction from Frequent Access.

Archive – Data that hasn’t been accessed for 90 or more days is stored in this tier, at a 65 percent cost reduction compared to Infrequent Access.

Regardless of the storage tier, your data is stored across multiple AWS Availability Zones for redundancy and availability, compared to typical on-premises implementations, which are usually confined within a single physical location. Additionally, your data can be retrieved instantly in milliseconds.

Creating a file system
I can create a file system using the AWS Management Console, AWS Command Line Interface (AWS CLI), API, or AWS CloudFormation. On the console, I choose Create file system to get started.


I select Amazon FSx for Lustre and choose Next.


Now, it’s time to enter the rest of the information to create the file system. I enter a name (veliswa_fsxINT_1) for my file system, and for deployment and storage class, I select Persistent, Intelligent-Tiering. I choose the desired Throughput capacity and the Metadata IOPS. The SSD read cache will be automatically configured by FSx for Lustre based on the specified throughput capacity. I leave the rest as the default, choose Next, and review my choices to create my file system.

With Amazon FSx for Lustre Intelligent-Tiering, you have the flexibility to provision the necessary performance for your workloads without having to provision any underlying storage capacity upfront.


I wanted to know which values were editable after creation, so I paid closer attention before finalizing the creation of the file system. I noted that Throughput capacity, Metadata IOPS, Security groups, SSD read cache, and a few others were editable later. After I start running the ML jobs, it might be necessary to increase the throughput capacity based on the volumes of data I’ll be processing, so this information is important to me.

The file system is now available. Considering that I’ll be running HPC workloads, I anticipate that I’ll be processing high volumes of data later, so I’ll increase the throughput capacity to 24 GB/s. After all, I only pay for the resources I use.


The SSD read cache is scaled automatically as your performance needs increase. You can adjust the cache size any time independently in user-provisioned mode or disable the read cache if you don’t need low-latency access.


Good to know

  • FSx for Lustre Intelligent-Tiering is designed to deliver up to multiple terabytes per second of total throughput.
  • FSx for Lustre with Elastic Fabric Adapter (EFA)/GPU Direct Storage (GDS) support provides up to 12x (up to 1200 Gbps) higher per-client throughput compared to the previous FSx for Lustre systems.
  • It can deliver up to tens of millions of IOPS for writes and cached reads. Data in the SSD read cache has submillisecond time-to-first-byte latencies, and all other data has time-to-first-byte latencies in the range of tens of milliseconds.

Now available
Here are a couple of things to keep in mind:

FSx Intelligent-Tiering storage class is available in the new FSx for Lustre file systems in the US East (N. Virginia, Ohio), US West (N. California, Oregon), Canada (Central), Europe (Frankfurt, Ireland, London, Stockholm), and Asia Pacific (Hong Kong, Mumbai, Seoul, Singapore, Sydney, Tokyo) AWS Regions.

You pay for data and metadata you store on your file system (GB/months). When you write data or when you read data that is not in the SSD read cache, you pay per operation. You pay for the total throughput capacity (in MBps/month), metadata IOPS (IOPS/month), and SSD read cache size for data and metadata (GB/month) you provision on your file system. To learn more, visit the Amazon FSx for Lustre Pricing page. To learn more about Amazon FSx for Lustre including this feature, visit the Amazon FSx for Lustre page.

Give Amazon FSx for Lustre Intelligent-Tiering a try in the Amazon FSx console today and send feedback to AWS re:Post for Amazon FSx for Lustre or through your usual AWS Support contacts.

– Veliswa.


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Introducing AWS Serverless MCP Server: AI-powered development for modern applications

Post Syndicated from Shridhar Pandey original https://aws.amazon.com/blogs/compute/introducing-aws-serverless-mcp-server-ai-powered-development-for-modern-applications/

Modern application development demands faster, more efficient ways to build and deploy software. Over the past decade, serverless computing has emerged as a transformative approach to software development, enabling developers to focus on building applications without having to manage the underlying infrastructure. As developers build their applications using AWS Serverless Compute, they seek guidance on selecting appropriate services, understanding best practices, and implementation patterns to make the most of this paradigm.

Today, AWS announces the open-source AWS Serverless Model Context Protocol (MCP) Server, a tool that combines the power of AI assistance with serverless expertise to enhance how developers build modern applications. The Serverless MCP Server provides contextual guidance specific to serverless development, helping developers make informed decisions about architecture, implementation, and deployment.

This post describes how the Serverless MCP Server works with AI coding assistants to streamline serverless development. Learn how to use this solution to accelerate your serverless development workflow and build robust, high-performing applications more efficiently.

Overview 

Serverless computing enables development teams to significantly reduce time-to-market while improving operational efficiency. Developers can focus on creating business value, while AWS services automatically handle scaling, availability, and infrastructure maintenance. AWS Lambda provides a seamless compute service where code runs in response to events, scaling instantly from a few requests per day to thousands per second. Through integration with over 200 AWS services, Lambda enables developers to build sophisticated applications using triggers from Amazon API Gateway, Amazon S3, Amazon DynamoDB, and many others. Whether you’re building data processing pipelines, real-time stream processing, or web applications, Lambda’s support for popular programming languages and development frameworks helps development teams leverage their existing skills while embracing the serverless paradigm.

MCP Server

MCP is an open protocol for AI agents to interact with external tools and data sources. It defines how AI assistants can discover, understand, and use various capabilities provided by external systems. This protocol allows AI models to extend their functionality beyond their own training data by accessing real-time information and executing specific tasks through standardized interfaces.

MCP servers implement this protocol by providing tools, resources, and contextual information that AI assistants can use via MCP clients. They serve as a knowledge bridge that gives AI assistants, such as Amazon Q Developer, Cline, and Cursor, the additional context needed to make informed decisions about cloud architecture and implementation. This is particularly valuable for serverless applications, where developers navigate multiple services, event patterns, and integration points to build scalable, performant applications.

AWS currently offers the AWS Lambda Tool MCP Server, which allows AI models to directly interact with existing Lambda functions as MCP tools without any code changes. This MCP server acts as a bridge between MCP clients and Lambda functions, allowing AI assistants to access and invoke Lambda functions.

Serverless MCP Server

The open-source AWS Serverless MCP launched today enhances the serverless development experience by providing AI coding assistants with comprehensive knowledge of serverless patterns, best practices, and AWS services. This MCP server acts as an intelligent companion, guiding developers through the entire application development lifecycle, from initial design to deployment, offering contextual assistance at each stage.

The new Serverless MCP server provides tools that cover many areas of serverless development. During the initial planning and setup phase, the MCP server helps developers initialize new projects using AWS Serverless Application Model (AWS SAM) templates, select appropriate Lambda runtimes, and set up project dependencies. This enables developers to quickly bootstrap new serverless applications with the right configuration and structure.

As development progresses, the MCP server assists with building and deploying serverless applications. It provides tools for local testing, building deployment artifacts, and managing deployments. For web applications, the MCP server offers specialized support for deploying backend, frontend, or full-stack applications, and setting up custom domains.

The MCP server also emphasizes operational excellence through comprehensive observability tools, helping developers to effectively monitor application performance and troubleshoot issues. Throughout the development process, the server provides contextual guidance for infrastructure as code (IaC) decisions, Lambda-specific best practices, and event schemas for Lambda event source mappings (ESMs).

Serverless MCP Server in action

To demonstrate the capabilities of the Serverless MCP Server, this example walks you through a scenario of creating, deploying, and troubleshooting a serverless application.

Prerequisites and installation

To get started, download the AWS Serverless MCP Server from GitHub or Python Package Index (PyPi) and follow the installation instructions. You can use this MCP server with any AI coding assistant of your choice, such as Q Developer, Cursor, Cline, etc. The walkthrough example in this post uses Cline.

Add the following code to your MCP client configuration. The Serverless MCP Server uses the default AWS profile by default. Specify a value in AWS_PROFILE if you want to use a different profile. Similarly, adjust the AWS Region and log level values as needed.

{
  "mcpServers": {
    "awslabs.aws-serverless-mcp": {
      "command": "uvx",
      "args": [
        "awslabs.aws_serverless_mcp_server@latest"
      ],
      "env": { 
        "AWS_PROFILE": "your-aws-profile",
        "AWS_REGION": "us-east-1",
        "FASTMCP_LOG_LEVEL": "ERROR"
      }
    }
  }
}

The Serverless MCP Server incorporates built-in guardrails to ensure secure and controlled development. By default, the MCP server operates in a read-only mode, allowing only non-mutating actions. This safety-first approach allows you to explore serverless capabilities and architectural patterns while preventing unintended changes to your applications or infrastructure. The server also restricts access to Amazon CloudWatch Logs by default, protecting sensitive operational data from exposure to AI assistants.

As your development needs evolve, you can selectively override these security defaults. The --allow-write flag enables mutating operations for tasks such as deployments and updates, while --allow-sensitive-data-access provides access to CloudWatch Logs for debugging and troubleshooting. Consider enabling these permissions only when necessary and in appropriate development contexts.

Creating and deploying a serverless application

Imagine that you want to build a to-do list web application. Start by prompting your AI assistant.

I want to build a new to-do list web application in a new workspace. I want to add, list, and delete to-dos. Would AWS Lambda be a good choice for this?

The agent uses the get_lambda_guidance_tool to receive tailored guidance based on the use case and the inferred event source, API Gateway in this case. Then, you want to better understand how to deploy the application to AWS.

I later want to deploy the application to AWS. Which Infrastructure as Code tool would be best for this?

There are several ways to deploy your functions to AWS such as AWS SAM or the AWS Cloud Development Kit (AWS CDK). The model opts to get more information before making a recommendation. It selects the get_iac_guidance_tool from the Serverless MCP Server.

The Serverless MCP Server can also assist you with interacting with the AWS Serverless Application Model Command Line Interface (AWS SAM CLI) as well as deploying application-based blueprints such as backend, frontend, or full-stack applications.

Before the deployment, test the function locally to verify that it works correctly.

I want to test my Lambda function locally before deploying it. Can you invoke the “TodoFunction” from my SAM project with a GET request?

Now that you are confident that the application works, you want to deploy the backend logic to AWS. So, you prompt the agent to deploy your app. It selects the deploy_webapp tool and provides the tool with arguments to deploy the app, including backend deploymentType. This tool uses the AWS Lambda Web Adapter framework, allowing you to easily deploy applications written in standard web frameworks like Express or Next.js, without any additional web adapters.

The agent can also check on the status of a deployment to make sure that it completes successfully.

Your application is now deployed to AWS and ready to serve traffic.

Troubleshooting the serverless application

The Serverless MCP Server also supports you in testing and troubleshooting your Lambda functions. It provides valuable context to AI assistants in identifying and remediating issues. For example, you can use your agent to check for any issues with your application.

Check the logs and metrics of the todo app for any issues

The model can analyze the logs and metrics and offer recommendations such as adjusting memory allocation.

The Serverless MCP Server tools provide the assistant with the additional context it needs to identify issues and generate recommendations.

In this example, the analysis and recommendations are:

Log Analysis

I’ve checked the logs for all three Lambda functions of your todo app, looking specifically for errors:

• ListTodosFunction: No errors detected
• AddTodoFunction: No errors detected
• DeleteTodoFunction: No errors detected

All functions are operating normally with successful executions and no error logs.

Performance Metrics

Lambda Function Performance
• Memory usage is reasonable at 100–106 MB out of 512 MB allocated (about 20% utilization)
• Fast execution durations for warm starts: 85–195 ms range
• No throttling or out-of-memory errors detected
• No function errors or exceptions in the logs

API Gateway Metrics
• Total Requests: 11 requests recorded
• Average Latency: 797 ms
• P95 Latency: 3364 ms (high)
• 4XX Errors: 0 (no client errors)
• 5XX Errors: 1 (one server error detected)

Issues Identified

The log analysis is clean with no errors, but the metrics reveal one potential issue:

  1. One 5XX Error in API Gateway: There was a single server-side error recorded in the API Gateway logs. Since there are no corresponding errors in the Lambda function logs, this might be related to:
    • A timeout (API Gateway taking too long to respond)
    • An integration issue between API Gateway and Lambda
    • A temporary network issue
  2. Relatively High P95 Latency: The 95th percentile latency of 3364 ms is quite high compared to the average. This suggests some outlier requests are taking significantly longer to complete.

Recommendations

  1. Monitor the 5XX error rate as it resurfaces.
  2. Consider implementing more detailed logging at the edge of the error path.
  3. Investigate the cause of the high P95 latency. Check for cold starts, payload size, or network latency as likely culprits.
  4. Consider enabling API Gateway and Lambda performance dashboards for more granular, historical latency and error metrics.
  5. Continue to monitor memory and duration metrics to ensure performance remains healthy as traffic increases.

Features supported by the Serverless MCP Server

The Serverless MCP Server provides several MCP tools, which can be classified into four categories.

  1. Serverless application lifecycle
    • sam_init_tool: Initializes a new AWS SAM project with the chosen runtime and dependencies.
    • sam_build_tool: Builds a serverless application using the AWS SAM CLI and prepares deployment artifacts.
    • sam_deploy_tool: Deploys a serverless application to AWS, managing artifact upload and stack creation.
    • sam_local_invoke_tool: Locally invokes a Lambda function for testing with custom events and environments.
  2. Web application deployment and management
    • deploy_webapp_tool: Deploys backend, frontend, or fullstack web applications to Lambda using the Lambda Web Adapter.
    • update_frontend_tool: Updates the frontend assets and optionally invalidates the Amazon CloudFront cache.
    • configure_domain_tool: Configures a custom domain, includes certificate and DNS setup.
  3. Observability
    • sam_logs_tool: Retrieves logs, and supports filtering and time range selection.
    • get_metrics_tool: Fetches specified metrics.
  4. Guidance, IaC templates, and deployment help
    • get_iac_guidance_tool: Provides guidance for selecting IaC tools.
    • get_lambda_guidance_tool: Offers advice on when to use Lambda for specific runtimes and use cases.
    • get_lambda_event_schemas_tool: Returns event schemas for Lambda integrations.
    • get_serverless_templates_tool: Supplies example AWS SAM templates for different serverless application types.
    • deployment_help_tool: Provides help and status information about deployments.
    • deploy_serverless_app_help_tool: Offers instructions for deploying serverless applications to Lambda.

Visit the Serverless MCP Server documentation for the full list of tools and resources.

Best practices and considerations

When building serverless applications with the AWS Serverless MCP Server, start by using its AI-assisted guidance for architectural decisions. Throughout development, use its guidance tools to make informed decisions about service selection, event patterns, and infrastructure design. Before deploying to AWS, use the Serverless MCP Server’s local testing capabilities to validate your application’s behavior. This approach helps ensure your application aligns with AWS best practices.

Robust monitoring and observability are critical to reliably operate your applications running in production. Use the Serverless MCP Server tools for deployment monitoring and setting up logging and metrics. This helps track application performance and quickly identify potential issues.

Conclusion

The open-source AWS Serverless MCP Server streamlines serverless application development by providing AI-assisted guidance throughout the development lifecycle. By combining AI assistance with serverless expertise, it enables developers to build and deploy applications more efficiently. The Serverless MCP Server’s toolset supports the complete development process, from initialization to observability, while helping developers implement AWS best practices.

As organizations continue to adopt serverless computing, tools that streamline development and accelerate delivery become increasingly valuable. AWS will continue to expand the collection of MCP servers for developers building serverless applications and refine existing tools based on customer feedback and emerging serverless development patterns.

To get started, visit the GitHub repository and explore the documentation. Share your experiences and suggestions through the GitHub repository to improve the MCP server’s capabilities and help shape the future of AI-assisted serverless development.

For more serverless learning resources, visit Serverless Land.

Elevate your AI security: Must-see re:Inforce 2025 sessions

Post Syndicated from Margaret Jonson original https://aws.amazon.com/blogs/security/reinforce-2025-genai-sessions/

AWS re:Inforce 2025: June 16-18 in Philadelphia, PA

A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.

From proof of concepts to large scale production deployments, the rapid advancement of generative AI has ushered in unique opportunities for innovation, but it also introduces a new set of security challenges (and opportunities) that organizations must address. How do you protect retrieval-augmented generation (RAG) or training data while maintaining model effectiveness? What controls are needed for large language model (LLM) interactions? How can I take full advantage of AI agents and model context protocol (MCP) while minimizing risk? At AWS re:Inforce 2025, we’re bringing together security experts, practitioners, and industry leaders to answer these questions with real-world, prescriptive guidance and more.

This year, our generative AI security sessions have been specifically curated and designed to help you build and maintain secure, production AI systems at scale. Whether you’re just beginning your AI security journey or leading mature, enterprise-wide AI initiatives, you’ll find deep practical guidance, hands-on experience, and strategic insights to advance your organization’s security posture.

From foundational concepts to advanced defensive techniques, these sessions encompass critical areas including data protection, model security, identity management, and AI agent resilience. You’ll learn directly from AWS security experts, customers who have successfully implemented secure AI systems, and industry leading partners who are setting new standards in AI safety and security.

In this blog, we highlight some “can’t miss” sessions that cover how to secure AI, but also how security practitioners can leverage AI to help with their critical security missions as well! Join in on the fun, and register for re:Inforce 2025!

Innovation talk

Engage with top AWS executives in our Innovation Talks series, where you’ll gain invaluable insights into the forefront of cloud technology. Explore the latest advancements in generative AI, discover robust cloud security strategies, and uncover pioneering architectural concepts that are revolutionizing application development and expanding the possibilities of the AWS Cloud.

SEC301 | Innovation Talk | From possibility to production: A strong, flexible foundation for AI security
Speakers: Hart Rossman (AWS) & Becky Weiss (AWS)
Discover how AWS removes the heavy lifting of AI security, enabling you to accelerate from development to production. This session reveals how the proven AWS security foundation, combined with flexible controls and automated reasoning, helps organizations confidently deploy AI innovations. Through real-world examples, learn how to transform security from a potential roadblock into an innovation enabler. Leave with practical guidance for securing AI workloads today and strategic insights into addressing emerging security challenges, including data security and agentic AI. Learn how the AWS approach to AI security helps you start ahead while maintaining strong security controls.

Breakout sessions, chalk talks, and lightning talks

Breakout sessions are lecture-style, one-hour sessions delivered by AWS experts, customers, and partners—perfect for deepening your knowledge on important topics, gaining actionable insights, and connecting with industry leaders.

Chalk talks are one-hour long, highly interactive sessions with a small audience. This format is ideal for diving deep into specific topics, engaging directly with AWS experts, and getting your questions answered in real time.

Lightning talks are short (20 minute) theater presentations dedicated to a specific customer story, service demo, or AWS Partner offering.

SEC303 | Breakout session | Behind the shields: AWS and Anthropic’s approach to secure AI
Speakers: Matt Saner (AWS) & Shahzeb Jiwani (Anthropic)
Enterprise AI adoption demands robust security. In this session, Join Anthropic’s head of risk governance along with AWS security leaders to reveal how AWS and Anthropic collaborate to deliver enterprise-grade security for LLMs and the generative AI workloads they enable. Learn about the multi-layered security approach spanning infrastructure, data, and models. We’ll explore real-world security architectures, governance frameworks, and risk mitigation strategies. You will leave with a deeper understanding of how to leverage AWS and Anthropic’s security capabilities to accelerate your organization’s AI initiatives while maintaining stringent security and compliance requirements.

SEC304 | Breakout session | Amazon.com testing frameworks and tools for GenAI security and privacy
Speakers: Alex Torres (AWS), Josh Haycraft (Amazon), & Jess Clark (Amazon)
GenAI solutions are launching in a unique, rapidly-shifting security landscape: they may be trained on customer data, they may integrate with internal services or datastores, and they will provide generated content to customers or to other systems. Learn how Amazon.com creates toolkits, systems and frameworks to leverage Large Language Models and Generative AI to enrich customer interactions to promote agility and innovation.

TDR301 | Breakout session | Innovations in AWS detection and response for integrated security outcomes
Speakers: Himanshu Verma (AWS) & Ryan Holland (AWS)
Discover how the latest AWS detection and response capabilities can help secure your cloud environment more effectively. Learn practical ways to achieve integrated security outcomes through enhanced threat detection, automated vulnerability management, and streamlined response – all at scale. We’ll show you how to use AWS security services to protect workloads and data, centralize security monitoring, manage security posture continuously, and unify security data, while leveraging generative AI for security operations. Walk away with actionable insights on integrating AWS detection and response services to strengthen and simplify your security across AWS.

SEC431 | Chalk talk | Dive deep into data protection architectures for Amazon Bedrock Agents
Speakers: Andrew Kane (AWS) & Gabrielle Dompreh (AWS)
Join this chalk talk to understand how Amazon Bedrock protects your data across Agents and related features, such as Knowledge Bases and Guardrails. Learn about security considerations for cross-region deployments, multi-agent collaboration, and prompt caching. Gain deep insights into architecting secure generative AI solutions that maintain data protection, and discover architectural patterns that keep your applications safe and secure.

APS231 | Chalk talk | Using AWS services to mitigate the OWASP Top 10 for LLM threats
Speakers: Mark Keating (AWS) & Cameron Smith (AWS)
You’ve identified your generative AI use case, tested it and are creating a secure application architecture design. How do you know what generative AI specific threats you should be protecting against, and what tools or services are available that can help? You may have heard of the OWASP Top 10 for LLM Applications, but where or how do you start? Join us as we discuss the OWASP Top 10 threats, the differences between versions, and how AWS can help you mitigate these threats.

DAP332 | Chalk talk | Executive perspective: Risk management for generative AI workloads
Speakers: Jason Garman (AWS) & Mark Ryland (AWS)
Don’t let the perceived complexity of responsible AI keep you from deploying generative AI applications on AWS. In this chalk talk, we will present a framework for breaking down AI safety and security risks, introduce AWS best practices for keeping enterprise data secure in generative AI applications using zero trust principles, and mitigate safety risks using technologies such as Bedrock Guardrails. Discover as a group with fellow security leaders how to identify safety and security risks relevant to your workload, implement appropriate mitigation strategies, and measure efficacy over time.

GRC337 | Chalk talk | Build compliant AI: Implementing controls for emerging regulations
Speakers: Samuel Waymouth (AWS) & Mark Keating (AWS)

As AI adoption accelerates, organizations face increasing regulatory scrutiny and compliance requirements. In this session, learn about the evolving global regulatory landscape for AI, data privacy, and data sovereignty, then see how you can map regulatory requirements and security controls to AWS services and features. We will demonstrate how generative AI can work as a tool for assessment, risk classification and generating compliance guidance. We also show you how to use the latest threat modelling resources developed by AWS. Security professionals and AI practitioners will learn actionable strategies for building AI systems aligned with compliance standards while also maintaining innovation velocity.

SEC221 | Lightning talk | Raising the tide: How AWS is shaping the future of secure AI
Speakers: Matt Saner (AWS)
AI security is a top priority for AWS. By building AI solutions that are secure by design, AWS helps customers innovate quickly with confidence while mitigating emerging threats. But securing AI goes beyond individual organizations—it requires industry-wide standards and best practices. AWS actively contributes to global AI security efforts, including its participation industry standards bodies such as CoSAI (The Coalition for Secure AI), to make sure AI technologies are safe, resilient, and trustworthy. This session will explore how AWS is leading AI security innovation, protecting customers, and collaborating to help shape the future of AI security for the entire industry.

SEC322 | Lightning talk | Managing digital identity in the age of generative AI
Speakers: Arthur Mnev (AWS) & Lily Ashidam (AWS)
In this session, we will explore the challenges and solutions for managing identities in generative AI workloads. This session covers securing API access for LLMs, implementing proper authentication for, in, and with AI services, and maintaining data lineage. Learn practical approaches towards securing generative AI applications while maintaining compliance and governance requirements.

SEC323 | Lightning talk | A practical guide to generative AI agent resilience
Speakers: Yiwen Zhang (AWS) & Jennifer Moran (AWS)
As generative AI agents dominate headlines and technological discussions, enterprise adoption remains in its infancy. GenAI agent resilience is a crucial factor in successful implementation and building user trust. While traditional workload resilience practices—such as database availability, workload capacity, observability, and disaster recovery—remain relevant, GenAI agents present unique challenges. This session delves into the critical dimensions of GenAI agent resilience, including LLM model adaptability, latency management, tool availability, observability, and financial sustainability. We will share practical strategies for building robust, reliable GenAI agents that enterprises can trust and maintain.

SEC326 | Lightning Talk | Secure remote MCP server deployment for Gen AI on AWS
Speakers: Aaron Brown (AWS) & James Ferguson (AWS)
Discover how to securely build and deploy remote Model Context Protocol (MCP) servers on AWS that implement the protocol’s security and trust principles. This session demonstrates OAuth 2.1 authorization patterns that enforce user consent, data privacy, and tool safety requirements. Learn to implement robust security controls using Amazon Cognito, API Gateway, and Lambda while maintaining protocol compliance. Explore practical examples of authorization flows, access controls, and security monitoring that align with MCP specifications.

TDR322 | Lightning talk | How AWS uses generative AI to advance native security services
Speakers: Marshall Jones (AWS) & Himanshu Verma (AWS)
Discover how AWS leverages generative AI to enhance native security services. This session demonstrates how AWS implements AI capabilities across its security portfolio to improve threat detection, investigation, and response. Explore practical implementations in Amazon GuardDuty and Amazon Inspector that enable automated analysis and natural language security queries. Leave with insights into how AWS makes security more intelligent and efficient through generative AI.

Interactive sessions (builders’ sessions, code talks, and workshops)

Interact with small groups led by an AWS expert providing interactive learning about how to build on AWS. Each builders’ session begins with a short explanation or demonstration of what attendees are building—then it’s your turn to build! The expert will guide you end-to-end through this hands-on experience. Or join Code Talks, our code-focused interactive sessions where AWS experts lead a discussion featuring live coding or code samples as they illuminate the “why” behind AWS solutions. Attendees are encouraged to ask questions and follow along.

Workshops are two-hour interactive sessions where you collaborate in teams or work individually to solve real-world challenges by using AWS services, making them perfect for hands-on learning. Each workshop begins with a brief lecture, followed by dedicated time to work through the problem.

Note: Don’t forget to bring your laptop to build alongside AWS experts.

SEC351 | Builders’ session | Accelerating incident response, compliance & auditing using generative AI
Speakers: Snehal Nahar (AWS), Ravindra Kori (AWS), Rayette Toles-Abdullah (AWS), & Abhijit Barde (AWS)
In this session, we will learn how to use AWS native generative AI capabilities to reduce time to recovery after an incident using enterprise communication tools such as Slack. We will also learn how to use detective controls to identify events that may result in an incident, and also how to use preventive controls to mitigate the risk of an incident occurring. We will use services like Amazon Q Developer, AWS Config, AWS CloudTrail Lake, Amazon CloudWatch and other observability features.

SEC352 | Builders’ session | Agentic AI for security: Building intelligent egress traffic controls
Speakers: Ranjith Rayaprolu (AWS), Anil Nadiminti (AWS), Michael Leighty (AWS), & Dwaragha Sivalingam (AWS)
Learn to build AI-powered security agents that protect your cloud infrastructure. This hands-on session shows you how to use Amazon Bedrock and Bedrock Agents to create intelligent systems that watch over your network. You’ll build Generative AI agents that monitor egress traffic, spot potential threats, and automatically update network firewall to block malicious traffic. Walk away with the skills to implement AI-powered security agents that can reason, decide, and act to protect your cloud infrastructure.

SEC353 | Builders’ session | Threat modeling for generative AI applications
Speakers: Laura Verghote (AWS), Isabelle Mos (AWS), Samuel Waymouth (AWS), & Omar Zoma (AWS)
In this builders’ session, you will learn how to systematically identify and analyze security threats specific to generative AI applications. As organizations rapidly adopt large language models and other generative AI capabilities, understanding the unique security challenges – from prompt injection to data poisoning – becomes critical. You will be guided through the process of creating threat models for common generative AI architectures, with a particular focus on applications built using AWS services like Amazon Bedrock.

SEC451 | Builders’ session | From logs to defense: Generative AI for security automation
Speakers: Ravindra Kori (AWS), Siavash Iran (AWS), Lily Ashidam (AWS), & Yiwen Zhang (AWS)
In this technical session, we’ll demonstrate how to transform traditional operating system log analysis into an intelligent, automated defense system using AWS native services and generative AI. We’ll explore how to build a comprehensive solution that captures security-relevant logs from Windows and Linux systems.

APS351 | Builders’ session | Securing generative AI agents using AWS Well-Architected Framework
Speakers: Krupanidhi Jay (AWS), Ryan Dsouza (AWS), Birender Pal (AWS), & Omkar Mukadam (AWS)
Learn hands-on how to build secure generative AI agent solutions following the AWS Well-Architected Framework’s Generative AI Lens security best practices. Work through practical implementations of endpoint security, prompt engineering guardrails, monitoring systems, and protection against excessive agency while building a production-ready generative AI agent. Through hands-on exercises, build a secure generative AI agent solution incorporating these controls on AWS, involving Amazon Bedrock, Amazon CloudWatch, AWS Identity and Access Management (IAM), and more. You must bring your laptop to participate.

APS353 | Builders’ session | Red teaming your LLM security at scale
Speakers: Otto Kruse (AWS), Owen Hawkins (AWS), Aaron Brown (AWS), & Jeff Lombardo (AWS)
Step into the shoes of an AI-powered red team adversary in the GenAI Red Team Challenge. In this intensive workshop, you’ll deploy an AI security agent to orchestrate sophisticated threat chains against GenAI applications, systematically discovering and exploiting vulnerabilities from prompt injection to boundary testing while mastering automated security testing workflows. In addition, you’ll learn to apply countermeasures, from prompt templating to guardrails. This hands-on, gamified experience helps you think like a threat actor and equips you with practical skills in automated vulnerability testing and risk mitigation against common MITRE and OWASP vulnerabilities for LLM-based applications. You must bring your laptop to participate.

GRC354 | Builders’ session | Best practices for using generative AI to manage cloud compliance
Speakers: Adnan Bilwani (AWS), Ali Maaz (AWS), Artur Rodrigues (AWS), & Peter Pereira (AWS)
Learn how to leverage Amazon Q Developer to streamline cloud compliance management using AWS Config. This hands-on builders’ session demonstrates how to create intelligent compliance checks, automate remediation workflows, and generate detailed compliance reports using generative AI capabilities. Through practical exercises, learn to implement automated compliance monitoring that combines the power of generative AI with AWS Config’s robust compliance framework. You must bring your laptop to participate.

IAM451 | Builders’ session | Securing GenAI apps: Fine-grained access control for Bedrock Agents
Speakers: Edward Sun (AWS), Pravin Nair (AWS), Dustin Ellis (AWS), & Kevin Hakanson (AWS)
Want to secure generative AI applications accessing your organizational data? Learn how to implement intelligent access controls for Amazon Bedrock-powered applications accessing your organizational data. In this builders’ session, you’ll build a defense-in-depth approach that combines authentication using Amazon Cognito and fine-grained authorization with Amazon Verified Permissions to secure access for Bedrock AI agents. Implement layered permissions that protect sensitive data without limiting your GenAI capabilities. You must bring your laptop to participate.

TDR251 | Builders’ session | Build your first AI security assistant with Amazon Q
Speakers: Scott Taggart (AWS), Joe Wagner (AWS), Laura Verghote (AWS), & Riggs Goodman III (AWS)
Discover how to build your first AI-powered security assistant using Amazon Q Business – no AI expertise required. In this hands-on session, you’ll create three practical security workflows: an automated Amazon GuardDuty incident investigator that contextualizes security findings, an AWS Security Hub compliance report generator that streamlines policy assessments, and an Amazon Inspector-based vulnerability management helper that accelerates remediation. Perfect for security practitioners who want to enhance AWS security operations with generative AI while mastering core AWS security services through practical application. You must bring your laptop to participate.

IAM441 | Code talk | The right way to secure AI agents with code examples
Speakers: Jeff Lombardo (AWS) & Fei Yuan (AWS)
Generative AI agents run tasks on behalf of human users and often interact with each other across on-premises environments and different cloud providers. This brings new challenges in identity authentication, propagation, delegation, and resource authorization in the overall agentic AI solution. Learn how Amazon Cognito’s OAuth2-based identity management, machine-to-machine authentication, combined with Amazon Verified Permissions fine-grained authorization can enable secure delegation patterns for AI agents, while preserving human identity and consent, agent machine identity, and other request context throughout the agent chain. We will walk through real-world examples with agents built on Amazon Bedrock or other frameworks.

TDR341 | Code talk | Build AI security agents with Amazon Bedrock and Amazon Security Lake
Speakers: Chris Lamont-Smith (AWS) & Pratima Singh (AWS)
In this code talk, explore how to enhance security operations by creating AI agents using Amazon Bedrock and Amazon Security Lake. Through live coding demonstrations, learn to build automated workflows that combine autonomous decision-making capabilities with generative AI for security analysis and response. See how to implement agents that analyze logs, provide contextual insights, and execute response procedures. Discover practical approaches for integrating custom tools and leveraging large language models in your security workflows.

SEC371 | Workshop | Red Team approaches to practical generative AI defenses
Speakers: Mac Stevens (AWS) & Cameron Smith (AWS)
This workshop takes a hands-on approach to Generative AI security, focusing on Amazon Bedrock, Amazon SageMaker, and related services. We’ll begin by examining Bedrock’s core security principles, including data protection during inference and in features like Agents, Guardrails, and Knowledge Bases. Participants will gain insights into the internal architectures and security implications of context windows, system prompts, agent orchestration, and more. The session then transitions into hands-on red teaming exercises using SageMaker. We’ll subsequently explore defensive strategies against these threat vectors and discuss methods for integrating these practices into development workflows. Participants will leave equipped with a holistic understanding of Generative AI security, from individual model protection to safeguarding complex, multi-component systems.

APS371 | Workshop | Securing your generative AI applications on AWS
Speakers: Mark Keating (AWS) & Maitreya Ranganath (AWS)
In this workshop, discover how to secure generative AI applications using AWS services and features. Explore how to deploy a vulnerable sample generative AI application and then layer security controls to protect, detect, and respond to security issues. Learn how to apply similar controls to the generative AI applications in your organization. You must bring your laptop to participate.

DAP371 | Workshop | Defend your AI: Mitigate prompt injection with Amazon Bedrock
Speakers: Mark Keating (AWS) & Maitreya Ranganath (AWS)
Master the art of identifying and mitigating prompt injection vulnerabilities in generative AI systems through this hands-on workshop. Using Amazon Bedrock, participants will explore both offensive and defensive prompt engineering techniques to understand the security implications of large language models in production environments. In this session you will understand how prompt injection attacks work, complete an interactive ‘capture the flag’ style challenge attempting to exploit a simulated AI environment, and learn to implement defensive controls using Amazon Bedrock Guardrails. You must bring your laptop to participate.

Register now

Don’t miss this opportunity to learn from industry experts and AWS leaders about securing your AI implementations. Register for AWS re:Inforce 2025 today to reserve your spot in these sessions. Browse the full re:Inforce catalog to learn more about sessions in other tracks, plus partner sessions and code talks.

If you have feedback about this post, submit comments in the Comments section below.

Margaret Jonson

Margaret Jonson

Margaret is a Senior Product Marketing Manager for AWS generative AI security, where she partners with AI/ML teams to help customers implement secure and governed AI solutions across Amazon Bedrock, Amazon SageMaker, Amazon Q, and other AI/ML solutions.

Matt Saner

Matt Saner

As a Senior Manager at AWS, Matt leads a team of security specialists who help the world’s most complex organizations tackle critical security challenges. Matt and his team work to transform security organizations into strategic business enablers. Before joining AWS, Matt spent close to two decades in the financial services industry. Outside of work, Matt is a pilot who finds joy in flying general aviation aircraft.

Navigating the threat detection and incident response track at re:Inforce 2025

Post Syndicated from Nisha Amthul original https://aws.amazon.com/blogs/security/navigating-the-threat-detection-and-incident-response-track-at-reinforce-2025/

AWS re:Inforce 2025: June 16-18 in Philadelphia, PA

A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.

We’re counting down to AWS re:Inforce, our annual cloud security event! We are thrilled to invite security enthusiasts and builders to join us in Philadelphia, PA June 16–18, 2025, for an immersive three-day journey into cloud security learning. At AWS re:Inforce, you’ll have the chance to explore the breadth of the Amazon Web Services (AWS) security landscape, learn how to operationalize security services, and enhance your skills and confidence in cloud security to improve your organization’s security posture. As an attendee, you will have access to over 250 sessions across multiple topic tracks, including data protection; identity and access management; threat detection and incident response; network and infrastructure security; generative AI; governance, risk, and compliance; and application security. Plus, get ready to be inspired by our lineup of customer speakers, who will share their firsthand experiences of innovating securely on AWS.

In this post, we provide an overview of the key sessions that include lecture-style presentations featuring real-world use cases from our customers and interactive small-group sessions led by AWS experts that guide you through practical problems and solutions.

The threat detection and incident response track is designed to demonstrate how to detect and respond to security risks to help protect workloads at scale. AWS experts and customers will present key topics such as unified cloud security, threat detection, vulnerability management, cloud security posture management, integrated detection-to-response, threat intelligence, operationalization of AWS security services, container security, effective security investigation, security analytics, and incident response best practices. We’ll also explore both strengthening security through the use of generative AI and securing generative AI workloads.

Breakout sessions, chalk talks, and lightning talks

TDR301 | Breakout session | Innovations in AWS detection and response for integrated security outcomes
Discover how AWS’s latest detection and response capabilities can help secure your cloud environment more effectively. Learn practical ways to achieve integrated security outcomes through enhanced threat detection, automated vulnerability management, and streamlined response—all at scale. We’ll show you how to use AWS security services to protect workloads and data, centralize security monitoring, manage security posture continuously, and unify security data, while leveraging generative AI for security operations. Walk away with actionable insights on integrating AWS detection and response services to strengthen and simplify your security across AWS.

TDR302 | Breakout session | Multi-stage threat detection using GuardDuty and MITRE
Enhance your threat detection capabilities by leveraging Amazon GuardDuty Extended Threat Detection alongside MITRE frameworks. In this session, Shane Steiger Esq. from MITRE Corp demonstrates how to effectively identify and respond to multi-stage security events in your AWS environment. Learn practical strategies for implementing detection controls, developing response procedures, and building resilient cloud architectures. Discover how integrating GuardDuty with MITRE frameworks can strengthen your event detection and response strategy.

TDR303 | Breakout session | Building secure generative AI security tools, featuring Trellix
Learn how to build enterprise-grade generative AI security tools that unify security data and enable natural language investigations. This session demonstrates practical approaches for developing secure generative AI solutions, including implementation patterns for data privacy and compliance controls. Explore real-world architectures combining AWS foundation models with security orchestration. Hear how Trellix achieved 23x cost savings while maintaining 95% accuracy using Amazon Bedrock models. Leave with strategies to build secure AI assistants that support your security teams.

TDR304 | Breakout session | Scaling AWS threat intelligence to protect customers
Discover how AWS builds and operates threat intelligence at unprecedented scale to protect millions of customers. In this session, dive deep into two critical security functions: Amazon Threat Intelligence, which tracks and defends against sophisticated threats, and Active Defense, our security data processing architecture that analyzes over 4 billion records per second. Learn how these capabilities work together to power AWS security services and provide automated protection for your applications. See how AWS uses this intelligence to continuously enhance security services that help keep your workloads safe.

TDR305 | Breakout session | Scale Vulnerability Management Using Amazon Inspector
Want to strengthen Lambda security and streamline vulnerability management? Learn how Amazon Inspector uses generative AI to provide in-context code patches and automate SBOM management. Discover practical techniques for CI/CD integration, cross-account scanning, and automated remediation workflows. Explore built-in integrations with Security Hub and EventBridge to enhance security operations across your AWS environment.

TDR306 | Breakout session | Enterprise Security at Scale: SAP’s AWS Blueprint
How does SAP protect thousands of AWS accounts? Learn their blueprint for implementing Amazon GuardDuty protection plans alongside Extended Threat Detection to identify sophisticated threat patterns. Discover their framework for standardizing AWS Security Hub controls and automated remediation workflows at scale. Walk away with practical strategies to enhance enterprise security operations across AWS Organizations.

TDR331 | Chalk talk | Ask AWS: Your ransomware questions answered
Get answers to your most critical ransomware questions in this interactive Q&A session. Learn how AWS security features and best practices can help you detect, respond to, and recover from ransomware threats. Our experts will share practical guidance on identifying early warning signs, implementing effective incident response, and strengthening your overall ransomware resilience. Bring your toughest questions about emerging ransomware tactics and cloud protection strategies. Walk away with actionable insights to help secure your data and operations using AWS security capabilities.

TDR332 | Chalk talk | Decoding AWS CIRT tactics & techniques for proactive defense
Learn directly from AWS Customer Incident Response Team (CIRT) experts who help customers respond to critical security events. Discover real-world insights about emerging threat tactics and techniques observed across AWS environments. We’ll share practical detection and mitigation strategies that align with the Shared Responsibility Model, helping you strengthen your security posture. Walk away with actionable best practices from CIRT’s frontline experience defending against evolving threats, and learn how to apply these insights to protect your AWS workloads.

TDR333 | Chalk talk | Strategy for prioritization and response
Join this session to discuss managing security posture and risk across multiple accounts, regions, and resources. We will explore the decision-making process around how you prioritize security alerts and risk using AWS security services. After prioritization, we will discuss a framework for responding to and remediating security findings. We will talk through the decision-making process of responding to findings, considerations for auto-remediation, and how to facilitate a quick and thorough response to the most critical security findings.

TDR334 | Chalk talk | Strengthen Security: Making GuardDuty Protection Plans Work for You
Discover how to maximize your threat detection capabilities by selecting the right Amazon GuardDuty protection plans for your environment. Learn to evaluate protection features that matter most for your AWS workloads and understand the value each plan brings to your security strategy. Through practical scenarios, explore cost-effective implementation strategies across your AWS accounts. Leave with actionable insights for optimizing your Amazon GuardDuty deployment to enhance protection of your AWS workloads and data.

TDR431 | Chalk talk | Best practices for containing AWS resources during incident response
Learn best practices for implementing isolation controls for AWS resources and accounts during security events. Through practical scenarios, discover effective approaches for isolating Amazon EC2 instances, AWS Lambda functions, and Amazon ECS containers. Explore comprehensive strategies for account-level isolation including identity, resource, and network controls. This session provides guidance on implementing and safely removing isolation controls as part of your response procedures. Leave with actionable patterns for strengthening your AWS incident response capabilities. To help businesses move faster and deliver security outcomes, modern security teams need to identify opportunities to automate and simplify their workflows. One way of doing so is through generative AI. Join this chalk talk to learn how to identify use cases where generative AI can help with investigating, prioritizing, and remediating findings from Amazon GuardDuty, Amazon Inspector, and AWS Security Hub. Then find out how you can develop architectures from these use cases, implement them, and evaluate their effectiveness. The talk offers tenets for generative AI and security that can help you safely use generative AI to reduce cognitive load and increase focus on novel, high-value opportunities.

TDR336 | Chalk talk | Secure generative AI models and agents on AWS
Learn how to strengthen security controls for generative AI models and Amazon Bedrock agents in your AWS environment. This session explores implementation patterns for protecting API endpoints and securing agent interactions. Discover practical approaches for implementing protective controls and maintaining data security for your AI/ML workloads. Leave with actionable strategies for building secure generative AI implementations using AWS services.

TDR337 | Chalk talk | Implementing AWS security best practices: Insights & strategies
Learn how to optimize your AWS security services implementation including Amazon GuardDuty, AWS Security Hub, and AWS WAF. AWS security experts share practical insights and proven patterns derived from thousands of customer deployments. This session provides actionable strategies for operationalizing security services effectively in your environment. Discover implementation best practices and architectural approaches that help you maximize the value of your AWS security services.

TDR338 | Chalk talk | Building cloud-native forensic investigation architectures on AWS
Join this chalk talk to explore the advantages of cloud-native digital forensics and incident response on AWS. Engage in interactive discussions on best practices for establishing secure forensic investigation environments. We’ll explore architectural patterns for safely collecting and storing forensic artifacts, leveraging ephemeral resources to enhance security, and implementing effective network, account, and organizational designs. Bring your questions and scenarios as we collaboratively examine how to build scalable, standardized investigation processes using AWS services. Leave with practical strategies for enhancing your forensic and incident response capabilities in the cloud.

TDR231 | Chalk talk | Resilient security teams: Reduce burnout and boost performance
Learn strategies for building resilient security and incident response teams that prioritize wellbeing while maintaining high performance. This session explores approaches for implementing regular team check-ins, data-informed wellbeing initiatives, and a supportive team culture. Discover practical methods for fostering open communication, maintaining team engagement, and recognizing team contributions. Through real-world examples, develop actionable plans to enhance team resilience, improve retention, and sustain security excellence. Leave with strategies to build and maintain high-performing security teams.

TDR321 | Lightning talk | From Incidents to Insights: Creating a Security Learning Organization
Learn how to transform security events into organizational improvements. This session demonstrates practical approaches for building effective feedback loops, preserving institutional knowledge, and implementing sustainable enhancements to security operations. Discover AWS strategies for measuring the impact of improvements and fostering a culture of continuous learning. Leave with actionable frameworks for strengthening your security program through systematic learning and adaptation.

TDR322 | Lightning talk | How AWS uses generative AI to advance native security services
Discover how AWS leverages generative AI to enhance native security services. This session demonstrates how AWS implements AI capabilities across its security portfolio to improve threat detection, investigation, and response. Explore practical implementations in Amazon GuardDuty and Amazon Inspector that enable automated analysis and natural language security queries. Leave with insights into how AWS makes security more intelligent and efficient through generative AI.

TDR323 | Lightning talk | How Autodesk scales threat detection with Amazon GuardDuty
Learn how Autodesk elevated their threat detection strategy using Amazon GuardDuty. This lightning talk explores their implementation approach, operational insights, and best practices for leveraging the advanced detection capabilities of GuardDuty, including malware protection. Discover how they maintain robust security while efficiently managing their growing cloud footprint.

TDR421 | Lightning talk | Accelerating Incident Response with AWS Security Incident Response
Learn how AWS Security Incident Response helps security teams streamline investigation and response procedures. This session demonstrates service integration capabilities with Amazon GuardDuty, AWS CloudTrail, and AWS Security Hub to provide centralized incident management. Through customer examples and implementation patterns, discover practical approaches for building automated response strategies. Leave with actionable insights for enhancing your security operations using AWS services.

Interactive sessions (builders’ sessions, code talks, and workshops)

TDR251 | Builders’ session | Build your first AI security assistant with Amazon Q
Discover how to build your first AI-powered security assistant using Amazon Q Business—no AI expertise required. In this hands-on session, you’ll create three practical security workflows: an automated Amazon GuardDuty incident investigator that contextualizes security findings, an AWS Security Hub compliance report generator that streamlines policy assessments, and an Amazon Inspector-based vulnerability management helper that accelerates remediation. Perfect for security practitioners who want to enhance AWS security operations with generative AI while mastering core AWS security services through practical application.

TDR252 | Builders’ session | Detect ransomware events in Amazon S3 using Amazon GuardDuty
In this builders’ session, join the AWS Customer Incident Response Team (CIRT) to implement Amazon S3 ransomware detection using Amazon GuardDuty. Through hands-on scenarios, learn to identify unauthorized encryption operations and implement effective response procedures. Build detection patterns using AWS CloudTrail, Amazon Athena, Amazon GuardDuty, and Amazon CloudWatch. Practice investigating events and implementing preventive measures aligned with AWS Security’s latest guidance for Amazon S3 object protection. You must bring your laptop to participate.

TDR351 | Builders’ session | Build an OCSF security log pipeline with AWS
Build a complete security log pipeline that leverages the Open Cybersecurity Schema Framework (OCSF) in this hands-on session. Work alongside AWS experts to ingest, transform, and enrich your security data. Learn practical techniques to standardize security logs, whether using your own schema or our provided examples. Walk away with implementable solutions to enhance your threat detection capabilities through normalized security data flows. Bring your laptop and optional custom log samples to create solutions tailored to your use cases.

TDR451 | Builders’ session | Automate incident response for Amazon EC2 and Amazon EKS
Learn how to streamline incident response using the Automated Forensics Orchestrator solution for Amazon Elastic Compute Cloud (Amazon EC2) and Amazon Elastic Kubernetes Service (Amazon EKS). This session demonstrates how to implement automated workflows triggered by AWS Security Hub findings. Explore implementation prerequisites, customization options, and best practices for enhancing your security operations through automated forensics capabilities. Discover how to standardize response procedures across your Amazon EC2 and Amazon EKS environments.

TDR452 | Builders’ session | Build generative AI security runbooks with Amazon Bedrock
In this builders’ session, learn how to enhance security operations using generative AI-powered runbooks with Amazon Bedrock and Bedrock Agents. Create intelligent workflows that analyze AWS Security Hub findings and provide contextual remediation guidance. Through hands-on exercises, build Bedrock Agents that leverage AWS documentation and implement natural language interfaces for security investigations. Learn how to configure knowledge bases with organization-specific content and implement appropriate guardrails. Leave with a practical solution for streamlining security operations using generative AI. You must bring your laptop to participate.

TDR341 | Code talk | Build AI security agents with Amazon Bedrock and Security Lake
In this code talk, explore how to enhance security operations by creating AI agents using Amazon Bedrock and Amazon Security Lake. Through live coding demonstrations, learn to build automated workflows that combine autonomous decision-making capabilities with generative AI for security analysis and response. See how to implement agents that analyze logs, provide contextual insights, and execute response procedures. Discover practical approaches for integrating custom tools and leveraging large language models in your security workflows.

TDR342 | Code talk | Operationalizing Amazon Security Lake with analytics and generative AI
Roll up your sleeves for this hands-on coding session where we’ll build modern security analytics tools on top of Amazon Security Lake. Through interactive demos, we’ll craft queries and visualizations to operationalize your security data using AWS services like Amazon OpenSearch Service, Amazon QuickSight, Amazon Athena, and Amazon Bedrock. Leave with practical code samples and architectures to analyze security data. Get inspired with ideas on how to transform your threat detection and incident response stack.

TDR343 | Code talk | From detection to code: GuardDuty attack sequences with Amazon Q
In this code talk, explore how Amazon GuardDuty attack sequence detection capabilities work alongside Amazon Q to enhance security operations. Through live coding demonstrations, learn hoGuardDuty machine learning models identify connected security events and create comprehensive event sequences. See how to build automated response procedures using Amazon Q AI-assisted development capabilities. Discover practical approaches for implementing context-aware security automation. Leave with implementation patterns for enhancing your security operations using generative AI tools.

TDR371 | Workshop | Hands-on Threat Detection & Response using AWS Security
Get hands-on experience with AWS security services in this interactive workshop. Learn to detect and respond to simulated threats using Amazon GuardDuty, Amazon Inspector, AWS Security Hub, and Amazon Detective. Practice both manual and automated response techniques with AWS Lambda as you investigate security events across different resource types. Walk away with practical skills to operationalize threat detection and response in your AWS environment. Bring your laptop to participate in this hands-on workshop.

TDR372 | Workshop | Secure container workloads with AWS security services
In this workshop, learn how to implement AWS security services to protect container workloads end-to-end from code to operations. Gain hands-on experience with static code analysis, detective controls, threat detection, vulnerability management, and incident response for Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS). Through guided scenarios, discover how to use AWS security services to enhance your container security posture. Leave with practical strategies for implementing security controls in your container environments. You must bring your laptop to participate.

TDR471 | Workshop | AWS Security Incident Response Challenge: Defense in action
Put your AWS security incident response skills to the test in this interactive session. Assume the role of an AWS Security Engineer responding to a time-sensitive scenario. Using provided intelligence, you’ll have a limited time to implement security controls in your AWS environment. Learn to prioritize actions and leverage AWS security services effectively under realistic conditions. This hands-on exercise helps you practice rapid decision-making and security implementation in AWS environments. Leave with practical experience in incident response strategies. You must bring your laptop to participate.

TDR472 | Workshop | Active defense strategies using AWS AI/ML services
This workshop will help you learn how to develop and deploy active defense strategies, such as deception, using Amazon Bedrock and Amazon SageMaker. Gain hands-on experience developing AI-driven responses for security operations. You will learn how to develop adaptive responses that mimic what an actor may be trying use against you. You will Learn implementation patterns for prompt engineering, deployment strategies, and monitoring methodologies. You must bring your laptop to participate.

Browse the full re:Inforce catalog to learn more about sessions in other tracks, plus gamified learning, innovation sessions, partner sessions, and labs. Discover how to optimize your re:Inforce journey with our attendee guides—your essential resource for selecting perfect learning sessions and getting the greatest value from your experience.

Our comprehensive track content is designed to help arm you with the knowledge and skills needed to securely manage your workloads and applications on AWS. Don’t miss out on the opportunity to stay updated with the latest best practices in threat detection and incident response. Join us in Philadelphia for re:Inforce 2025 by registering today. We can’t wait to welcome you!

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Nisha Amthul

Nisha Amthul

Nisha is a Senior Product Marketing Manager at AWS Security, specializing in detection and response solutions. She has a strong foundation in product management and product marketing within the domains of information security and data protection. When not at work, you’ll find her cake decorating, strength training, and chasing after her two energetic kiddos.

AWS Weekly Roundup: Claude 4 in Amazon Bedrock, EKS Dashboard, community events, and more (May 26, 2025)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-4-in-amazon-bedrock-eks-dashboard-community-events-and-more-may-26-2025/

As the tech community we continue to have many opportunities to learn and network with other like-minded folks. This past week AWS customers attended the AWS Summit Dubai for an action-packed day featuring live demos, hands-on experiences with cutting-edge AI/ML tools, and more. Right here in South Africa I attended the Data & AI Community in Durban for a day of inspiration and learning from the community. In India, the AWS Community Day Bengaluru brought together hundreds of passionate tech enthusiasts for a day of learning and networking.

Last week’s launches
Here are the launches that got my attention:

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Additional updates
Here are some additional projects, blog posts, and news items that you might find interesting:

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Tel Aviv (May 28), Singapore (May 29), Stockholm (June 4), Sydney (June 4–5), Washington (June 10-11), and Madrid (June 11).
  • AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Milwaukee, USA (June 5), and Nairobi, Kenya (June 14).

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Veliswa.

OpenSearch UI: Six months in review

Post Syndicated from Muthu Pitchaimani original https://aws.amazon.com/blogs/big-data/opensearch-ui-six-months-in-review/

OpenSearch UI has been adopted by thousands of customers for various use cases since its launch in November 2024. Exciting customer stories and feedback have helped shape our feature improvements. As we complete 6 months since its general availability, we are sharing major enhancements that have improved OpenSearch UI’s capability, especially in observability and security analytics, in this post.

OpenSearch UI is a serverless, fully managed dashboard to provide a scalable, zero-downtime, web-based interface for data analytics and visualizations. With OpenSearch UI, you can have a unified interface to gain actionable insights across multiple data sources, including Amazon OpenSearch Service domains, Amazon OpenSearch Serverless collections, and AWS services such as Amazon CloudWatch and Amazon Security Lake.

Use natural language for your AI-powered analytics with Amazon Q Developer

OpenSearch UI has transformed complex data analysis to be as simple as asking questions in natural language with its integration with Amazon Q Developer in OpenSearch. You can access the conversational chat pane by choosing the Amazon Q Developer icon in the top right corner of the UI. Amazon Q Developer will answer generic questions such as how to use the features in OpenSearch UI and how to use OpenSearch UI with additional data sources.

You can use the search bar on the Discover page to use the generative AI capabilities with your OpenSearch data. You can enter your question about your data in natural language. The query assistant feature will translate your question to Piped Processing Language (PPL), run the query, and show the results. There will also be an Amazon Q Summary section generated from the query results to answer your question. The query assistant feature now also works with data connections from Amazon Simple Storage Service (Amazon S3).

Additionally, you can use the generative AI feature for anomaly detection and visualizations for your data, so it’s straightforward to identify potential issues earlier and faster, reducing the mean time to resolution.

When an alert is triggered, you can choose the Amazon Q icon to generate a summary of the alert, so you can catch up on the context of this alert. The View insights button will provide further analysis of the alerts in combination with OpenSearch knowledge through a process called Retrieval Augmented Generation (RAG). If you want to further investigate the alert, you can choose View in Discover to proceed to log analytics.

Amazon Q Developer in OpenSearch Service will help you reduce troubleshooting time, resolve more issues without escalation, and extract actionable insights from your operational data using natural language instead of specialized queries. Refer to Amazon Q Developer in Amazon OpenSearch Service to get started with the AI assisted analytics experience.

Enhance enterprise security

We have improved OpenSearch UI’s security capability to meet the demanding needs of large enterprises. Through these enhancements, we’re making it seamless to manage secure access at scale so you can have precise control over who can access your analytics workspaces and data that resides in them.

Use SAML workflows through IAM federation

OpenSearch UI now supports Security Assertion Markup Language (SAML) through AWS Identity and Access Management (IAM) federation so that you can create a single sign-on (SSO) experience for your end-users that initiates authentication workflows from your external identity providers (IdPs), typically called IdP-initiated SSO. You might find this process familiar if your organization is using external IdPs (such as Okta) to manage user permissions and track user activities in accessing AWS services. You can now define a default relay state URL to share with your end-users with this support. Your end-users can use this URL to land directly in OpenSearch UI after authenticating with their IdP. You can also achieve fine-grained access control by defining different permissions for each IAM role assumed by different end-users. To get started, refer to Enabling SAML federation with AWS Identity and Access Management.

Secure access with AWS PrivateLink

OpenSearch UI now supports AWS PrivateLink. You can now access OpenSearch UI privately from within your virtual private cloud (VPC). To learn more, see Managing access to the OpenSearch UI from a VPC endpoint.

Enhancing workspace privacy

There are also new workspace-level privacy settings, so you can quickly configure your workspace with the right permissions with collaborators. For more details, refer to Using Amazon OpenSearch Service workspaces.

Expanded data access capabilities

OpenSearch UI now also offers following additional data access capabilities.

Support for cross-cluster search

Cross-cluster search is an OpenSearch feature with which you can query multiple connected OpenSearch Service domains across accounts and across AWS Regions. We added the capability to support these connected domains as data sources in OpenSearch UI. With this support, you can view remote connected clusters with an index pattern under the data source for the source cluster. To learn more, see Cross-Region and cross-account data access with cross-cluster search.

Regional expansion

To further expand the data access capabilities of OpenSearch UI, we expanded its availability to two more regions: Asia Pacific (Hong Kong) and Europe (Stockholm).

Conclusion

The past 6 months after general availability of OpenSearch UI have seen significant progress in making OpenSearch UI more user-friendly, more available, and more secure. From natural language-based exploration to enterprise security, these feature enhancements reflect our commitment to simplify and improve your data analytics experience. To learn more, refer to Using OpenSearch UI in Amazon OpenSearch Service and get updates through Amazon OpenSearch Service user interface release history.


About the Authors

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Hang (Arthur) Zuo is a Senior Product Manager with Amazon OpenSearch Service. Arthur leads generative AI, workspaces, and infrastructural features in OpenSearch UI. Arthur is passionate about cloud technologies and building data products that help users and businesses gain actionable insights and achieve operational excellence.

Introducing Claude 4 in Amazon Bedrock, the most powerful models for coding from Anthropic

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/claude-opus-4-anthropics-most-powerful-model-for-coding-is-now-in-amazon-bedrock/

Anthropic launched the next generation of Claude models today—Opus 4 and Sonnet 4—designed for coding, advanced reasoning, and the support of the next generation of capable, autonomous AI agents. Both models are now generally available in Amazon Bedrock, giving developers immediate access to both the model’s advanced reasoning and agentic capabilities.

Amazon Bedrock expands your AI choices with Anthropic’s most advanced models, giving you the freedom to build transformative applications with enterprise-grade security and responsible AI controls. Both models extend what’s possible with AI systems by improving task planning, tool use, and agent steerability.

With Opus 4’s advanced intelligence, you can build agents that handle long-running, high-context tasks like refactoring large codebases, synthesizing research, or coordinating cross-functional enterprise operations. Sonnet 4 is optimized for efficiency at scale, making it a strong fit as a subagent or for high-volume tasks like code reviews, bug fixes, and production-grade content generation.

When building with generative AI, many developers work on long-horizon tasks. These workflows require deep, sustained reasoning, often involving multistep processes, planning across large contexts, and synthesizing diverse inputs over extended timeframes. Good examples of these workflows are developer AI agents that help you to refactor or transform large projects. Existing models may respond quickly and fluently, but maintaining coherence and context over time—especially in areas like coding, research, or enterprise workflows—can still be challenging.

Claude Opus 4
Claude Opus 4 is the most advanced model to date from Anthropic, designed for building sophisticated AI agents that can reason, plan, and execute complex tasks with minimal oversight. Anthropic benchmarks show it is the best coding model available on the market today. It excels in software development scenarios where extended context, deep reasoning, and adaptive execution are critical. Developers can use Opus 4 to write and refactor code across entire projects, manage full-stack architectures, or design agentic systems that break down high-level goals into executable steps. It demonstrates strong performance on coding and agent-focused benchmarks like SWE-bench and TAU-bench, making it a natural choice for building agents that handle multistep development workflows. For example, Opus 4 can analyze technical documentation, plan a software implementation, write the required code, and iteratively refine it—while tracking requirements and architectural context throughout the process.

Claude Sonnet 4
Claude Sonnet 4 complements Opus 4 by balancing performance, responsiveness, and cost, making it well-suited for high-volume production workloads. It’s optimized for everyday development tasks with enhanced performance, such as powering code reviews, implementing bug fixes, and new feature development with immediate feedback loops. It can also power production-ready AI assistants for near real-time applications. Sonnet 4 is a drop-in replacement from Claude Sonnet 3.7. In multi-agent systems, Sonnet 4 performs well as a task-specific subagent—handling responsibilities like targeted code reviews, search and retrieval, or isolated feature development within a broader pipeline. You can also use Sonnet 4 to manage continuous integration and delivery (CI/CD) pipelines, perform bug triage, or integrate APIs, all while maintaining high throughput and developer-aligned output.

Opus 4 and Sonnet 4 are hybrid reasoning models offering two modes: near-instant responses and extended thinking for deeper reasoning. You can choose near-instant responses for interactive applications, or enable extended thinking when a request benefits from deeper analysis and planning. Thinking is especially useful for long-context reasoning tasks in areas like software engineering, math, or scientific research. By configuring the model’s thinking budget—for example, by setting a maximum token count—you can tune the tradeoff between latency and answer depth to fit your workload.

How to get started
To see Opus 4 or Sonnet 4 in action, enable the new model in your AWS account. Then, you can start coding using the Bedrock Converse API with model IDanthropic.claude-opus-4-20250514-v1:0 for Opus 4 and anthropic.claude-sonnet-4-20250514-v1:0 for Sonnet 4. We recommend using the Converse API, because it provides a consistent API that works with all Amazon Bedrock models that support messages. This means you can write code one time and use it with different models.

For example, let’s imagine I write an agent to review code before merging changes in a code repository. I write the following code that uses the Bedrock Converse API to send a system and user prompts. Then, the agent consumes the streamed result.

private let modelId = "us.anthropic.claude-sonnet-4-20250514-v1:0"

// Define the system prompt that instructs Claude how to respond
let systemPrompt = """
You are a senior iOS developer with deep expertise in Swift, especially Swift 6 concurrency. Your job is to perform a code review focused on identifying concurrency-related edge cases, potential race conditions, and misuse of Swift concurrency primitives such as Task, TaskGroup, Sendable, @MainActor, and @preconcurrency.

You should review the code carefully and flag any patterns or logic that may cause unexpected behavior in concurrent environments, such as accessing shared mutable state without proper isolation, incorrect actor usage, or non-Sendable types crossing concurrency boundaries.

Explain your reasoning in precise technical terms, and provide recommendations to improve safety, predictability, and correctness. When appropriate, suggest concrete code changes or refactorings using idiomatic Swift 6
"""
let system: BedrockRuntimeClientTypes.SystemContentBlock = .text(systemPrompt)

// Create the user message with text prompt and image
let userPrompt = """
Can you review the following Swift code for concurrency issues? Let me know what could go wrong and how to fix it.
"""
let prompt: BedrockRuntimeClientTypes.ContentBlock = .text(userPrompt)

// Create the user message with both text and image content
let userMessage = BedrockRuntimeClientTypes.Message(
    content: [prompt],
    role: .user
)

// Initialize the messages array with the user message
var messages: [BedrockRuntimeClientTypes.Message] = []
messages.append(userMessage)

// Configure the inference parameters
let inferenceConfig: BedrockRuntimeClientTypes.InferenceConfiguration = .init(maxTokens: 4096, temperature: 0.0)

// Create the input for the Converse API with streaming
let input = ConverseStreamInput(inferenceConfig: inferenceConfig, messages: messages, modelId: modelId, system: [system])

// Make the streaming request
do {
    // Process the stream
    let response = try await bedrockClient.converseStream(input: input)

    // Iterate through the stream events
    for try await event in stream {
        switch event {
        case .messagestart:
            print("AI-assistant started to stream"")

        case let .contentblockdelta(deltaEvent):
            // Handle text content as it arrives
            if case let .text(text) = deltaEvent.delta {
                self.streamedResponse + = text
                print(text, termination: "")
            }

        case .messagestop:
            print("\n\nStream ended")
            // Create a complete assistant message from the streamed response
            let assistantMessage = BedrockRuntimeClientTypes.Message(
                content: [.text(self.streamedResponse)],
                role: .assistant
            )
            messages.append(assistantMessage)

        default:
            break
        }
    }

To help you get started, my colleague Dennis maintains a broad range of code examples for multiple use cases and a variety of programming languages.

Available today in Amazon Bedrock
This release gives developers immediate access in Amazon Bedrock, a fully managed, serverless service, to the next generation of Claude models developed by Anthropic. Whether you’re already building with Claude in Amazon Bedrock or just getting started, this seamless access makes it faster to experiment, prototype, and scale with cutting-edge foundation models—without managing infrastructure or complex integrations.

Claude Opus 4 is available in the following AWS Regions in North America: US East (Ohio, N. Virginia) and US West (Oregon). Claude Sonnet 4 is available not only in AWS Regions in North America but also in APAC, and Europe: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Hyderabad, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), and Europe (Spain). You can access the two models through cross-Region inference. Cross-Region inference helps to automatically select the optimal AWS Region within your geography to process your inference request.

Opus 4 tackles your most challenging development tasks, while Sonnet 4 excels at routine work with its optimal balance of speed and capability.

Learn more about the pricing and how to use these new models in Amazon Bedrock today!

— seb

Centralize visibility of Kubernetes clusters across AWS Regions and accounts with EKS Dashboard

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/centralize-visibility-of-kubernetes-clusters-across-aws-regions-and-accounts-with-eks-dashboard/

Today, we are announcing EKS Dashboard, a centralized display that enables cloud architects and cluster administrators to maintain organization-wide visibility across their Kubernetes clusters. With EKS Dashboard, customers can now monitor clusters deployed across different AWS Regions and accounts through a unified view, making it easier to track cluster inventory, assess compliance, and plan operational activities like version upgrades.

As organizations scale their Kubernetes deployments, they often run multiple clusters across different environments to enhance availability, ensure business continuity, or maintain data sovereignty. However, this distributed approach can make it challenging to maintain visibility and control, especially in decentralized setups spanning multiple Regions and accounts. Today, many customers resort to third-party tools for centralized cluster visibility, which adds complexity through identity and access setup, licensing costs, and maintenance overhead.

EKS Dashboard simplifies this experience by providing native dashboard capabilities within the AWS Console. The Dashboard provides insights into 3 different resources including clusters, managed node groups, and EKS add-ons, offering aggregated insights into cluster distribution by Region, account, version, support status, forecasted extended support EKS control plane costs, and cluster health metrics. Customers can drill down into specific data points with automatic filtering, enabling them to quickly identify and focus on clusters requiring attention.

Setting up EKS Dashboard

Customers can access the Dashboard in EKS console through AWS Organizations’ management and delegated administrator accounts. The setup process is straightforward and includes simply enabling trusted access as a one-time setup in the Amazon EKS console’s organizations settings page. Trusted access is available from the Dashboard settings page. Enabling trusted access will allow the management account to view the Dashboard. For more information on setup and configuration, see the official AWS Documentation.

Screenshot of EKS Dashboard settings

A quick tour of EKS Dashboard

The dashboard provides both graphical, tabular, and map views of your Kubernetes clusters, with advanced filtering, and search capabilities. You can also export data for further analysis or custom reporting.

Screenshot of EKS Dashboard interface

EKS Dashboard overview with key info about your clusters.

Screenshot of EKS Dashboard interface

There is a wide variety of available widgets to help visualize your clusters.

Screenshot of EKS Dashboard interface

You can visualize your managed node groups by instance type distribution, launch templates, AMI versions, and more

Screenshot of EKS Dashboard interface

There is even a map view where you can see all of your clusters across the globe.

Beyond EKS clusters

EKS Dashboard isn’t limited to just Amazon EKS clusters; it can also provide visibility into connected Kubernetes clusters running on-premises or on other cloud providers. While connected clusters may have limited data fidelity compared to native Amazon EKS clusters, this capability enables truly unified visibility for organizations running hybrid or multi-cloud environments.

Available now

EKS Dashboard is available today in the US East (N. Virginia) Region and is able to aggregate data from all commercial AWS Regions. There is no additional charge for using the EKS Dashboard. To learn more, visit the Amazon EKS documentation.

This new capability demonstrates our continued commitment to simplifying Kubernetes operations for our customers, enabling them to focus on building and scaling their applications rather than managing infrastructure. We’re excited to see how customers use EKS Dashboard to enhance their Kubernetes operations.

— Micah;

Amazon Q Developer CLI supports image inputs in your terminal

Post Syndicated from Keerthi Sreenivas Konjety original https://aws.amazon.com/blogs/devops/amazon-q-developer-cli-supports-image-inputs-in-your-terminal/

In this post I will explore how the image support feature in Amazon Q Developer Command Line Interface (CLI) transforms development workflows. Q Developer CLI recently added image support, expanding its capabilities to process visual information and enhancing developer productivity. This new feature allows developers to interact with diagrams, architecture blueprints, and other visual assets directly through the command line.

Modern software development increasingly relies on visual representations to communicate ideas. For example, architecture diagrams illustrate system components and their interactions, while entity-relationship diagrams map out database structures. Translating visual assets into working code is usually a manual, error-prone process of interpretation and implementation.

The new image support in Q Developer CLI bridges this gap by allowing developers to provide images directly to the Q Developer CLI agent for analysis. I’m excited to use this feature to transform my architecture diagrams from scrappy, hand-drawn ideas to polished design documents, and then to infrastructure as code. I look forward to applying it in various use cases, whether I’m getting started on a new project or streamlining my daily workflows.

At the time of launch, the Q Developer CLI supports JPEG, PNG, WEBP, and GIF image formats along with the ability to upload 10 images per request. You must use the latest version (1.10.0 or above) of Q developer CLI to enjoy the image support feature in Q Developer CLI. Use this guide to upgrade or install the latest version.

I will use the following four scenarios as examples to demonstrate the benefit of image support for Q Developer CLI.

Use-case 1: Generating infrastructure as code from an architecture diagram

The following diagram depicts an application that resizes images. It includes a source Amazon S3 bucket into which a user uploads an image, and an AWS Lambda function that resizes the image and stores it in a destination S3 Bucket. I can now convert architecture diagrams to code using Q Developer CLI.

AWS architecture diagram showing an image resizing workflow. The diagram illustrates a source S3 bucket connected to an AWS Lambda function, which then connects to a destination S3 bucket. The flow represents an automated image resizing pipeline.

Architecture for an image resizing application

In the following screenshot, I asked the Q Developer CLI to “Please provide me with a reference terraform template using best practices”. Note that dragging and dropping the image into the CLI will add the path to your prompt.

Screenshot of Amazon Q Developer CLI interface showing generated Terraform code for S3 buckets and Lambda function configuration based on the uploaded architecture diagram

CLI with Terraform code generated by Q Developer

The prior image shows a portion of the response that Q Developer CLI has generated.

Q Developer responds with the terraform template required to get started with building the image resizing application. Q Developer CLI analyzed the image, identified the components and their relationships, and generated the corresponding Terraform code. While not shown in the image, the response included the Lambda function’s code in Python and the IAM permissions needed for the Lambda function.

Previously, transforming this diagram into infrastructure as code would require me to manually interpret each component and write the corresponding configuration. With image support, I can now automate much of this process and refine the generated code through a conversation with Q Developer. I can then have a conversation with Q Developer to refine the generated code, ask questions about specific implementation details, or request modifications based on additional requirements and output the code to a .tf file.

Use-case 2: Converting ER diagrams to database schemas

For our second scenario, let’s consider a use case where I’m a part of a data modeling team developing a course management software for universities. I have created an entity-relationship (ER) diagram for their core data structures. I can now use Q developer to help me convert the ER diagram to SQL.

Image shows an Entity Relationship Diagram with relationships between entities such as Courses, Students, Instructors, and Departments with their attributes.

Course management Entity Relationship Diagram

In the following screenshot, I asked the Q Developer CLI to use the ER diagram to create the database schema.

Screenshot of Amazon Q Developer CLI interface showing the beginning of a generated design document with system architecture and process flow sections based on the hand-drawn diagram

CLI with user prompt and SQL generated by Q Developer

The image shows a continuation of SQL Code response from Amazon Q Developer CLI for table creation generated from the ER Diagram reference.

CLI with SQL generated by Q Developer

The prior image shows the response the that Q Developer CLI generated.

Q Developer analyzed the diagram, identified entities, attributes, and relationships, then generated the appropriate SQL code for creating the database schema.

After Q Developer produces the results, I can refine this schema through a conversation with Q Developer by requesting changes to string lengths, indexes, etc., or requesting explanations of design decisions.

Use-case 3: Converting a hand drawn image to a design document

Consider a scenario where I have brainstormed an idea on paper and I would like to share this with my team. In the following image, I have hand drawn the order flow for a website. When the website user orders books from the website, the application updates inventory, then calls the payment and delivery actions. I can now use the Q Developer CLI to draft documentation from the hand drawn idea.

Hand-drawn flowchart showing the order process for a book website, including steps for order placement, inventory update, payment processing, and delivery actions

Hand drawn order flow for a website

In the following example, I asked Q Developer to write a design document using this image as a reference.

Amazon Q Developer CLI interface showing a command prompt with image input and the resulting generated code response.

CLI with user prompt and response generated by Q Developer

The above screenshot shows that, Q Developer first read the image and understood the content from the hand drawn diagram image.

The image shows a continuation of Design documentation response from Amazon Q Developer CLI for table creation generated from the ER Diagram reference.

CLI with the response generated by Q Developer

The prior screen shot is a portion of the response that Q Developer CLI has generated.

Q Developer converted the idea into a design document including system architecture, process flow, data model, functional requirements, and technical requirements. I can also ask Q Developer to output the context to a .md file. This reduces the amount of time going from idea to execution and streamlines document writing.

Use-case 4: Building a UI mockup/wireframe from a screen shot

Let’s say, I want to get started with building a User Interface (UI) from my design document from use-case 3. I can provide a reference image to Q Developer for generating initial wireframes for my UI.

Screenshot of a sample book sales website.

Sample book sales website home page

In this example, I asked Q Developer to help generate a front-end for a new website in Vue.js

Amazon Q Developer CLI interface showing a command prompt with image input and the resulting generated code response. The screenshot shows Amazon Q Developer CLI generating Vue.js setup instructions

CLI with the user prompt and response generated by Q Developer

The image shows a continuation of Vue.js code response from Amazon Q Developer CLI that uses the book wesbite screenshot as a reference.

CLI with Vue.js code generated by Q Developer

The prior image shows a portion of the Vue.js code generated by the Q Developer CLI to re-produce the front-end of the website in the screenshot. Once I verify the code, I can then ask Q Developer CLI to create these files locally.

This approach reduces the error-prone aspects of wireframe creation, allowing me to focus on creative design decisions instead of repetitive setup tasks. In this way, I can accelerate development cycles, ensure consistency across components, and provide a foundation that can be easily customized to meet specific project requirements.

Additional possibilities:

Apart from the prior examples, Q Developer CLI can analyze many types of images, including:

  • Flow charts and process diagrams
  • Class diagrams for object-oriented design
  • Network topology diagrams
  • Screenshots of error messages or application states

This versatility makes Q Developer CLI a powerful tool for various development workflows.

Conclusion:

The addition of image support to Amazon Q Developer CLI represents a significant step forward in bridging the gap between visual and textual representations in software development. By allowing me to work with diagrams and other visual assets directly from the command line, Amazon Q Developer improves my efficiency in translating design into implementation, reducing errors and accelerating development cycles. I encourage you to explore this new capability and discover how it can enhance your development workflow.

To learn more about Q Developer and its capabilities, visit the documentation.

About the Author: 

Authors-image

Keerthi Sreenivas Konjety

Keerthi Sreenivas Konjety is a Specialist Solutions Architect for Amazon Q Developer, with over 3.5 years of experience in AI, ML and Data Engineering. Her expertise lies in enabling developer productivity for AWS customers. Outside work, she enjoys photography and AI content creation.

Configure System Integrity Protection (SIP) on Amazon EC2 Mac instances

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/configure-system-integrity-protection-sip-on-amazon-ec2-mac-instances/

I’m pleased to announce developers can now programmatically disable Apple System Integrity Protection (SIP) on their Amazon EC2 Mac instances. System Integrity Protection (SIP), also known as rootless, is a security feature introduced by Apple in OS X El Capitan (2015, version 10.11). It’s designed to protect the system from potentially harmful software by restricting the power of the root user account. SIP is enabled by default on macOS.

SIP safeguards the system by preventing modification of protected files and folders, restricting access to system-owned files and directories, and blocking unauthorized software from selecting a startup disk. The primary goal of SIP is to address the security risk linked to unrestricted root access, which could potentially allow malware to gain full control of a device with just one password or vulnerability. By implementing this protection, Apple aims to ensure a higher level of security for macOS users, especially considering that many users operate on administrative accounts with weak or no passwords.

While SIP provides excellent protection against malware for everyday use, developers might occasionally need to temporarily disable it for development and testing purposes. For instance, when creating a new device driver or system extension, disabling SIP is necessary to install and test the code. Additionally, SIP might block access to certain system settings required for your software to function properly. Temporarily disabling SIP grants you the necessary permissions to fine-tune programs for macOS. However, it’s crucial to remember that this is akin to briefly disabling the vault door for authorized maintenance, not leaving it permanently open.

Disabling SIP on a Mac requires physical access to the machine. You have to restart the machine in recovery mode, then disable SIP with the csrtutil command line tool, then restart the machine again.

Until today, you had to operate with the standard SIP settings on EC2 Mac instances. The physical access requirement and the need to boot in recovery mode made integrating SIP with the Amazon EC2 control plane and EC2 API challenging. But that’s no longer the case! You can now disable and re-enable SIP at will on your Amazon EC2 Mac instances. Let me show you how.

Let’s see how it works
Imagine I have an Amazon EC2 Mac instance started. It’s a mac2-m2.metal instance, running on an Apple silicon M2 processor. Disabling or enabling SIP is as straightforward as calling a new EC2 API: CreateMacSystemIntegrityProtectionModificationTask. This API is asynchronous; it starts the process of changing the SIP status on your instance. You can monitor progress using another new EC2 API: DescribeMacModificationTasks. All I need to know is the instance ID of the machine I want to work with.

Prerequisites
On Apple silicon based EC2 Mac instances and more recent type of machines, before calling the new EC2 API, I must set the ec2-user user password and enable secure token for that user on macOS. This requires connecting to the machine and typing two commands in the terminal.

# on the target EC2 Mac instance
# Set a password for the ec2-user user
~ % sudo /usr/bin/dscl . -passwd /Users/ec2-user
New Password: (MyNewPassw0rd)

# Enable secure token, with the same password, for the ec2-user
# old password is the one you just set with dscl
~ % sysadminctl -newPassword MyNewPassw0rd -oldPassword MyNewPassw0rd
2025-03-05 13:16:57.261 sysadminctl[3993:3033024] Attempting to change password for ec2-user…
2025-03-05 13:16:58.690 sysadminctl[3993:3033024] SecKeychainCopyLogin returned -25294
2025-03-05 13:16:58.690 sysadminctl[3993:3033024] Failed to update keychain password (-25294)
2025-03-05 13:16:58.690 sysadminctl[3993:3033024] - Done

# The error about the KeyChain is expected. I never connected with the GUI on this machine, so the Login keychain does not exist
# you can ignore this error.  The command below shows the list of keychains active in this session
~ % security list
    "/Library/Keychains/System.keychain"

# Verify that the secure token is ENABLED
~ % sysadminctl -secureTokenStatus ec2-user
2025-03-05 13:18:12.456 sysadminctl[4017:3033614] Secure token is ENABLED for user ec2-user

Change the SIP status
I don’t need to connect to the machine to toggle the SIP status. I only need to know its instance ID. I open a terminal on my laptop and use the AWS Command Line Interface (AWS CLI) to retrieve the Amazon EC2 Mac instance ID.

 aws ec2 describe-instances \
         --query "Reservations[].Instances[?InstanceType == 'mac2-m2.metal' ].InstanceId" \
         --output text

i-012a5de8da47bdff7

Now, still from the terminal on my laptop, I disable SIP with the create-mac-system-integrity-protection-modification-task command:

echo '{"rootVolumeUsername":"ec2-user","rootVolumePassword":"MyNewPassw0rd"}' > tmpCredentials
aws ec2 create-mac-system-integrity-protection-modification-task \
--instance-id "i-012a5de8da47bdff7" \
--mac-credentials fileb://./tmpCredentials \
--mac-system-integrity-protection-status "disabled" && rm tmpCredentials

{
    "macModificationTask": {
        "instanceId": "i-012a5de8da47bdff7",
        "macModificationTaskId": "macmodification-06a4bb89b394ac6d6",
        "macSystemIntegrityProtectionConfig": {},
        "startTime": "2025-03-14T14:15:06Z",
        "taskState": "pending",
        "taskType": "sip-modification"
    }
}

After the task is started, I can check its status with the aws ec2 describe-mac-modification-tasks command.

{
    "macModificationTasks": [
        {
            "instanceId": "i-012a5de8da47bdff7",
            "macModificationTaskId": "macmodification-06a4bb89b394ac6d6",
            "macSystemIntegrityProtectionConfig": {
                "debuggingRestrictions": "",
                "dTraceRestrictions": "",
                "filesystemProtections": "",
                "kextSigning": "",
                "nvramProtections": "",
                "status": "disabled"
            },
            "startTime": "2025-03-14T14:15:06Z",
            "tags": [],
            "taskState": "in-progress",
            "taskType": "sip-modification"
        },
...

The instance initiates the process and a series of reboots, during which it becomes unreachable. This process can take 60–90 minutes to complete. After that, when I see the status in the console becoming available again, I connect to the machine through SSH or EC2 Instance Connect, as usual.

➜  ~ ssh [email protected]
Warning: Permanently added '54.99.9.99' (ED25519) to the list of known hosts.
Last login: Mon Feb 26 08:52:42 2024 from 1.1.1.1

    ┌───┬──┐   __|  __|_  )
    │ ╷╭╯╷ │   _|  (     /
    │  └╮  │  ___|\___|___|
    │ ╰─┼╯ │  Amazon EC2
    └───┴──┘  macOS Sonoma 14.3.1

➜  ~ uname -a
Darwin Mac-mini.local 23.3.0 Darwin Kernel Version 23.3.0: Wed Dec 20 21:30:27 PST 2023; root:xnu-10002.81.5~7/RELEASE_ARM64_T8103 arm64

➜ ~ csrutil --status 
System Integrity Protection status: disabled.

When to disable SIP
Disabling SIP should be approached with caution because it opens up the system to potential security risks. However, as I mentioned in the introduction of this post, you might need to disable SIP when developing device drivers or kernel extensions for macOS. Some older applications might also not function correctly when SIP is enabled.

Disabling SIP is also required to turn off Spotlight indexing. Spotlight can help you quickly find apps, documents, emails and other items on your Mac. It’s very convenient on desktop machines, but not so much on a server. When there is no need to index your documents as they change, turning off Spotlight will release some CPU cycles and disk I/O.

Things to know
There are a couple of additional things to know about disabling SIP on Amazon EC2 Mac:

  • Disabling SIP is available through the API and AWS SDKs, the AWS CLI, and the AWS Management Console.
  • On Apple silicon, the setting is volume based. So if you replace the root volume, you need to disable SIP again. On Intel, the setting is Mac host based, so if you replace the root volume, SIP will still be disabled.
  • After disabling SIP, it will be enabled again if you stop and start the instance. Rebooting an instance doesn’t change its SIP status.
  • SIP status isn’t transferable between EBS volumes. This means SIP will be disabled again after you restore an instance from an EBS snapshot or if you create an AMI from an instance where SIP is enabled.

These new APIs are available in all Regions where Amazon EC2 Mac is available, at no additional cost. Try them today.

— seb


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Introducing the AWS Product Lifecycle page and AWS service availability updates

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/introducing-the-aws-product-lifecycle-page-and-aws-service-availability-updates/

Today, we’re introducing the AWS Product Lifecycle page, a centralized resource that provides comprehensive information about service availability changes across AWS.

The new AWS Product Lifecycle page consolidates all service availability information in one convenient location. This dedicated resource offers detailed visibility into three key categories of changes: 1) services closing access to new customers, 2) services that have announced end of support, and 3) services that have reached their end of support date. For each service listed, you can access specific end-of-support dates, recommended migration paths, and links to relevant documentation, enabling more efficient planning for service transitions.

The AWS Product Lifecycle page helps you stay informed about changes that may affect your workloads and enables more efficient planning for service transitions. The centralized nature of this resource reduces the time and effort needed to track service lifecycle information, allowing you to focus more on your core business objectives and less on administrative overhead.

Today on the new Product Lifecycle page, you will see updates about the following changes to services and capabilities:

AWS service availability updates in 2025
After careful consideration, we’re announcing availability changes for a select group of AWS services and features. We understand that the decision to end support for a service or feature significantly impacts your operations. We approach such decisions only after thorough evaluation, and when end of support is necessary, we provide detailed guidance on available alternatives and comprehensive support for migration.

Services closing access to new customers
We’re closing access to new customers after June 20, 2025, for the following services or capabilities listed. Existing customers will be able to continue to use the service.

Services that have announced end of support
The following services will no longer be supported. To find out more about service specific end-of-support dates, as well as detailed migration information, please visit individual service documentation pages.

Services that have reached their end of support
The following services have reached their end of support date and can no longer be accessed:

  • AWS Private 5G
  • AWS DataSync Discovery

The AWS Product Lifecycle page is available and all the changes described in this post are listed on the new page now. We recommend that you bookmark this page and check out What’s New with AWS? for upcoming AWS service availability updates. For more information about using this new resource, contact us or your usual AWS Support contacts for specific guidance on transitioning affected workloads.

— seb

Exploring the latest features of the Amazon Q Developer CLI

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/exploring-the-latest-features-of-the-amazon-q-developer-cli/

It’s been a few weeks since my last post about the Amazon Q Developer Command Line Interface (CLI), and I’m excited to share all the great new features and improvements the team has been working on. The CLI has been evolving rapidly with a focus on enhancing user experience, improving context management, and adding powerful new capabilities. In this post, I’ll walk you through the most significant changes that make the Amazon Q Developer CLI even more powerful and user-friendly.

Conversation Persistence

One of the most requested features has been the ability to persist conversations, and I’m thrilled to share that this is now available. With the new q chat --resume command, your conversations are now automatically saved by a working directory. This means you can pick up right where you left off when you return to a project, without having to rebuild context or repeat information.

Q Developer has also added two new commands to give you more control over your conversation state:

  • /save allows you to explicitly save the current conversation state
  • /load lets you restore a previously saved conversation

These commands make it easier to manage multiple conversation threads related to different aspects of your project. You can save a conversation about one feature, switch to working on something else, and then load the previous conversation when you’re ready to continue.

A terminal interface showing the Amazon Q logo in dotted cyan text. Below it displays a 'Did you know?' tip explaining that users can resume the last conversation from their current directory using 'q chat --resume'. The bottom shows command shortcuts including '/help' for all commands, 'ctrl + j' for new lines, and 'ctrl + s' for fuzzy search. The terminal shows a successful import of conversation state from 'order-service.json'.

MCP and Tool Use Enhancements

The Model Context Protocol (MCP) is a key part of the Amazon Q Developer CLI, allowing for extensibility through additional tools and servers. Q Developer has made several improvements to how MCP servers are loaded and managed:

First, Q Developer has implemented background MCP server loading, which significantly improves startup time for q chat. Instead of waiting for all MCP servers to initialize before you can start interacting with Q Developer, the CLI now loads servers in the background while you begin your conversation. This means you can start working immediately, with tools becoming available as their servers finish loading.

The team has also added a new subcommand, q mcp, which provides a dedicated interface for updating and managing your MCP server configuration. This makes it easier to add, remove, or modify the MCP servers that extend your CLI’s capabilities.

For more granular control over which tools can be used, Q Developer has added the /tools command in q chat. This allows you to manage permissions for individual tools, giving you more control over what Q Developer can do in your environment. You can also reset permissions for a specific tool if you change your mind.

A terminal window showing a tools permission list with two main sections. The first section shows SQLite (MCP) commands, all marked as 'not trusted' including operations like list_tables, read_query, create_table, etc. The second 'Built-in' section lists system commands with varying trust levels: fs_read and report_issue are marked as 'trusted', while fs_write is 'not trusted', and use_aws and execute_bash are marked for 'trust read-only commands'. At the bottom, there's a note stating 'Trusted tools can be run without confirmation'.

Improved Context Control

Context is crucial for getting the most out of Q Developer, and the team has made several improvements to how you can manage and view context:

The file selection in q chat‘s fuzzy finder is now git-aware, making it easier to include relevant files from your repository. This is particularly useful when working with large codebases, as it helps you focus on the files that matter for your current task.

Q Developer has added fuzzy search for slash commands with Ctrl + s, allowing you to quickly find and execute commands without remembering their exact syntax. This makes the CLI more accessible, especially for new users or those who don’t use certain commands frequently.

The /context show --expand command has been improved to provide more detailed information about the current context, helping you understand what Q Developer knows about your environment. The team has also enhanced the context file display in q chat to make it more informative and easier to read.

One of the most exciting additions is the new capability for dynamically adding context to messages with context hooks. This allows the CLI to automatically include relevant context based on your conversation, improving the quality of responses without requiring manual context management.

A terminal window showing an expanded context view with two main sections. The 'global' section (marked with a globe icon) lists three markdown files: amazonq/rules/**/*.md, README.md, and AmazonQ.md. It includes hooks for 'On Session Start' and 'Per User Message', both showing '<none>‘. Below that, a ‘profile (default)’ section (marked with a user icon) shows ~/python-coding-standards.md and has the same hook structure, also with ‘<none>‘ values. The command shown at the top is ‘/context show –expand’.” width=”1140″ height=”624″></p>
<h2>Context Window Awareness and Optimization</h2>
<p>As conversations grow longer, managing the context window becomes increasingly important. Q Developer has added two new commands to help with this:</p>
<ul>
<li><code>/usage</code> displays an estimate of the context window usage, helping you understand how much of the available context space you’re using</li>
<li><code>/compact</code> summarizes the conversation history, allowing you to reduce the size of the context while preserving the important information</li>
</ul>
<p>These tools help you make the most of the available context window, ensuring that Q Developer has access to the most relevant information without running into token limits.</p>
<p><img decoding=

Image Support

I’m particularly excited to announce that q chat now supports images! This opens up a whole new dimension of interaction, allowing you to share screenshots, diagrams, or other visual information with Q Developer. This can be incredibly useful for debugging UI issues, discussing design concepts, or explaining complex ideas that are difficult to convey through text alone.

A text explanation of a UML sequence diagram for a Sales Transaction process. The text describes three main components: 1) Participants including an Actor (represented by a stick figure) and a System (represented by a rectangle), 2) Interaction Flow showing message exchanges and lifelines represented by vertical dashed lines, and 3) Loop Structure with a box labeled 'for as many items as needed' representing an iteration where the Actor scans items with product ID and amount parameters.

Editor for Long Prompts

For complex queries or detailed instructions, you may want multiple paragraphs. Q Developer supports Ctrl + j, allowing you to add a newline character to the prompt. In addition, the team has added the /editor command, which opens your configured text editor for composing prompts. This makes it much easier to craft detailed, multi-paragraph prompts or to edit and refine your questions before sending them to Q Developer.

A screenshot showing instructions for performing a threat model analysis using the STRIDE framework. The text requests threat analysis details in markdown format, including threat source, prerequisites, actions, impacts, and affected assets. It asks for severity ratings (low/medium/high) and AWS-based mitigation suggestions with documentation links. The image includes a template structure showing how to format the markdown response, with sections for "Threat Model Analysis," "Spoofing," and individual threat entries.

Expanded Region Support

I’m happy to announce that Q Developer has expanded its regional availability. Professional tier users can now access Q Developer in the Frankfurt region (eu-central-1). This expansion is part of Q Developer’s ongoing effort to provide lower latency and better service to customers across the globe. By adding support for the Frankfurt region, Amazon Q Developer is more accessible to European customers, allowing them to benefit from reduced latency and improved performance.

A terminal screenshot showing a prompt to select an IAM Identity Center profile. Two options are displayed: "q-dev-america" with an ARN in the us-east-1 region, and "q-dev-emea" with an ARN in the eu-central-1 region. The command being executed is "% q profile".

Ability to Manage Issues in CLI

Amazon Q Developer has made it easier to report issues directly from the CLI with two new features:

  • The /issue command in q chat allows you to create new GitHub issues
  • The report_issue tool provides a programmatic way for Q Developer to help you create detailed issue reports

These features streamline the feedback process, making it easier for you to report bugs or request features, and for the team to improve the CLI based on your input.

A terminal screenshot showing an issue reporting interface. The prompt explains how to submit feedback or feature requests to a GitHub repository, listing required information including: 1) a title and 2) optional details about actual behavior, expected behavior, and reproduction steps. At the bottom is a user comment stating "I just wanted you to know that all these new features are awesome!"

Keeping Up with Future Changes

To help you stay informed about new features and improvements, Q Developer has added a --changelog flag to the q version command. This displays the change log directly from the CLI, making it easy to see what’s new without having to visit the GitHub repository or read blog posts like this one.

Conclusion

The Amazon Q Developer CLI continues to evolve rapidly, with new features and improvements that make it an even more powerful tool for developers. From conversation persistence to image support, these updates reflect Q Developer’s commitment to building a CLI that helps you be more productive and effective in your daily work. I encourage you to try out these new features by installing the Amazon Q Developer CLI. Thank you for your continued support and feedback, which helps make Amazon Q Developer better every day.

Amazon Inspector enhances container security by mapping Amazon ECR images to running containers

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/amazon-inspector-enhances-container-security-by-mapping-amazon-ecr-images-to-running-containers/

When running container workloads, you need to understand how software vulnerabilities create security risks for your resources. Until now, you could identify vulnerabilities in your Amazon Elastic Container Registry (Amazon ECR) images, but couldn’t determine if these images were active in containers or track their usage. With no visibility if these images were being used on running clusters, you had limited ability to prioritize fixes based on actual deployment and usage patterns.

Starting today, Amazon Inspector offers two new features that enhance vulnerability management, giving you a more comprehensive view of your container images. First, Amazon Inspector now maps Amazon ECR images to running containers, enabling security teams to prioritize vulnerabilities based on containers currently running in your environment. With these new capabilities, you can analyze vulnerabilities in your Amazon ECR images and prioritize findings based on whether they are currently running and when they last ran in your container environment. Additionally, you can see the cluster Amazon Resource Name (ARN), number EKS pods or ECS tasks where an image is deployed, helping you prioritize fixes based on usage and severity.

Second, we’re extending vulnerability scanning support to minimal base images including scratch, distroless, and Chainguard images, and extending support for additional ecosystems including Go toolchain, Oracle JDK & JRE, Amazon Corretto, Apache Tomcat, Apache httpd, WordPress (core, themes, plugins), and Puppeteer, helping teams maintain robust security even in highly optimized container environments.

Through continual monitoring and tracking of images running on containers, Amazon Inspector helps teams identify which container images are actively running in their environment and where they’re deployed, detecting Amazon ECR images running on containers in Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Kubernetes Service (Amazon EKS), and any associated vulnerabilities. This solution supports teams managing Amazon ECR images across single AWS accounts, cross-account scenarios, and AWS Organizations with delegated administrator capabilities, enabling centralized vulnerability management based on container images running patterns.

Let’s see it in action
Amazon ECR image scanning helps identify vulnerabilities in your container images through enhanced scanning, which integrates with Amazon Inspector to provide automated, continual scanning of your repositories. To use this new feature you have to enable enhanced scanning through the Amazon ECR console, you can do it by following the steps in the Configuring enhanced scanning for images in Amazon ECR documentation page. I already have Amazon ECR enhanced scanning, so I don’t have to do any action.

In the Amazon Inspector console, I navigate to General settings and select ECR scanning settings from the navigation panel. Here, I can configure the new Image re-scan mode settings by choosing between Last in-use date and Last pull date. I leave it as it is by default with Last in-use date and set the Image last in use date to 14 days. These settings make it so that Inspector monitors my images based on when they were running in the last 14 days in my Amazon ECS or Amazon EKS environments. After applying these settings, Amazon Inspector starts tracking information about images running on containers and incorporating it into vulnerability findings, helping me focus on images actively running in containers in my environment.

After it’s configured, I can view information about images running on containers in the Details menu, where I can see last in-use and pull dates, along with EKS pods or ECS tasks count.

When selecting the number of Deployed ECS Tasks/EKS Pods, I can see the cluster ARN, last use dates, and Type for each image.

For cross-account visibility demonstration, I have a repository with EKS pods deployed in two accounts. In the Resources coverage menu, I navigate to Container repositories, select my repository name and choose the Image tag. As before, I can see the number of deployed EKS pods/ECS tasks.

When I select the number of deployed EKS pods/ECS tasks, I can see that it is running in a different account.

In the Findings menu, I can review any vulnerabilities, and by selecting one, I can find the Last in use date and Deployed ECS Tasks/EKS Pods involved in the vulnerability under Resource affected data, helping me prioritize remediation based on actual usage.

In the All Findings menu, you can now search for vulnerabilities within account management, using filters such as Account ID, Image in use count and Image last in use at.

Key features and considerations
Monitoring based on container image lifecycle – Amazon Inspector now determines image activity based on: image push date ranging duration 14, 30, 60, 90, or 180 days or lifetime, image pull date from 14, 30, 60, 90, or 180 days, stopped duration from never to 14, 30, 60, 90, or 180 days and status of image running on the container. This flexibility lets organizations tailor their monitoring strategy based on actual container image usage rather than only repository events. For Amazon EKS and Amazon ECS workloads, last in use, push and pull duration are set to 14 days, which is now the default for new customers.

Image runtime-aware finding details – To help prioritize remediation efforts, each finding in Amazon Inspector now includes the lastInUseAt date and InUseCount, indicating when an image was last running on the containers and the number of deployed EKS pods/ ECS tasks currently using it. Amazon Inspector monitors both Amazon ECR last pull date data and images running on Amazon ECS tasks or Amazon EKS pods container data for all accounts, updating this information at least once daily. Amazon Inspector integrates these details into all findings reports and seamlessly works with Amazon EventBridge. You can filter findings based on the lastInUseAt field using rolling window or fixed range options, and you can filter images based on their last running date within the last 14, 30, 60, or 90 days.

Comprehensive security coverage – Amazon Inspector now provides unified vulnerability assessments for both traditional Linux distributions and minimal base images including scratch, distroless, and Chainguard images through a single service. This extended coverage eliminates the need for multiple scanning solutions while maintaining robust security practices across your entire container ecosystem, from traditional distributions to highly optimized container environments. The service streamlines security operations by providing comprehensive vulnerability management through a centralized platform, enabling efficient assessment of all container types.

Enhanced cross-account visibility – Security management across single accounts, cross-account setups, and AWS Organizations is now supported through delegated administrator capabilities. Amazon Inspector shares images running on container information within the same organization, which is particularly valuable for accounts maintaining golden image repositories. Amazon Inspector provides all ARNs for Amazon EKS and Amazon ECS clusters where images are running, if the resource belongs to the account with an API, providing comprehensive visibility across multiple AWS accounts. The system updates deployed EKS pods or ECS tasks information at least one time daily and automatically maintains accuracy as accounts join or leave the organization.

Availability and pricing – The new container mapping capabilities are available now in all AWS Regions where Amazon Inspector is offered at no additional cost. To get started, visit the AWS Inspector documentation. For pricing details and Regional availability, refer to the AWS Inspector pricing page.

PS: Writing a blog post at AWS is always a team effort, even when you see only one name under the post title. In this case, I want to thank Nirali Desai, for her generous help with technical guidance, and expertise, which made this overview possible and comprehensive.

— Eli


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

AWS Weekly Roundup: Strands Agents, AWS Transform, Amazon Bedrock Guardrails, AWS CodeBuild, and more (May 19, 2025)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-strands-agents-aws-transform-amazon-bedrock-guardrails-aws-codebuild-and-more-may-19-2025/

Many events are taking place in this period! Last week I was at the AI Week in Italy. This week I’ll be in Zurich for the AWS Community Day – Switzerland. On May 22, you can join us remotely for AWS Cloud Infrastructure Day to learn about cutting-edge advances across compute, AI/ML, storage, networking, serverless technologies, and global infrastructure. Look for events near you for an opportunity to share your knowledge and learn from others.

What got me particularly excited last Friday was the introduction of Strands Agents, an open source SDK that you can use to build and run AI agents in just a few lines of code. It can scale from simple to complex use cases, including local development and production deployment. By default, it uses Amazon Bedrock as model provider, but many others are supported, including Ollama (to run models locally), Anthropic, Llama API, and LiteLLM (to provide a unified interface for other providers such as Mistral). With Strands, you can use any Python function as a tool for your agent with the @tool decorator. Strands provides many example tools for manipulating files, making API requests, and interacting with AWS APIs. You can also choose from thousands of published Model Context Protocol (MCP) servers, including this suite of specialized MCP servers that help you get the most out of AWS. Multiple teams at AWS already use Strands for their AI agents in production, including Amazon Q Developer, AWS Glue, and VPC Reachability Analyzer. Read it all in Clare’s post.

Strands Agents SDK agentic loop

Last week’s launches
Here are the other launches that got my attention:

Additional updates
Here are some additional projects, blog posts, and news items that you might find interesting:

  • Securing Amazon S3 presigned URLs for serverless applications – Focusing on the security ramifications of using Amazon S3 presigned URLs, explaining mitigation steps that developers can take to improve the security of their systems using S3 presigned URLs, and walking through an AWS Lambda function that adheres to the provided recommendations.
    Architectural diagram.
  • Running GenAI Inference with AWS Graviton and Arcee AI Models – While large language models (LLMs) are capable of a wide variety of tasks, they require compute resources to support hundreds of billions and sometimes trillions of parameters. Small language models (SLMs) in contrast typically have a range of 3 to 15 billion parameters and can provide responses more efficiently. In this post, we share how to optimize SLM inference workloads using AWS Graviton based instances.
    AWS Graviton processors.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Dubai (May 21), Tel Aviv (May 28), Singapore (May 29), Stockholm (June 4), Sydney (June 4–5), Washington (June 10-11), and Madrid (June 11)
  • AWS Cloud Infrastructure Day – On May 22, discover the latest innovations in AWS Cloud infrastructure technologies at this exclusive technical event.
  • AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity.
  • AWS Partners Events – You’ll find a variety of AWS Partner events that will inspire and educate you, whether you’re just getting started on your cloud journey or you’re looking to solve new business challenges.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Zurich, Switzerland (May 22), Bengaluru, India (May 23), Yerevan, Armenia (May 24), Milwaukee, USA (June 5), and Nairobi, Kenya (June 14)

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Danilo