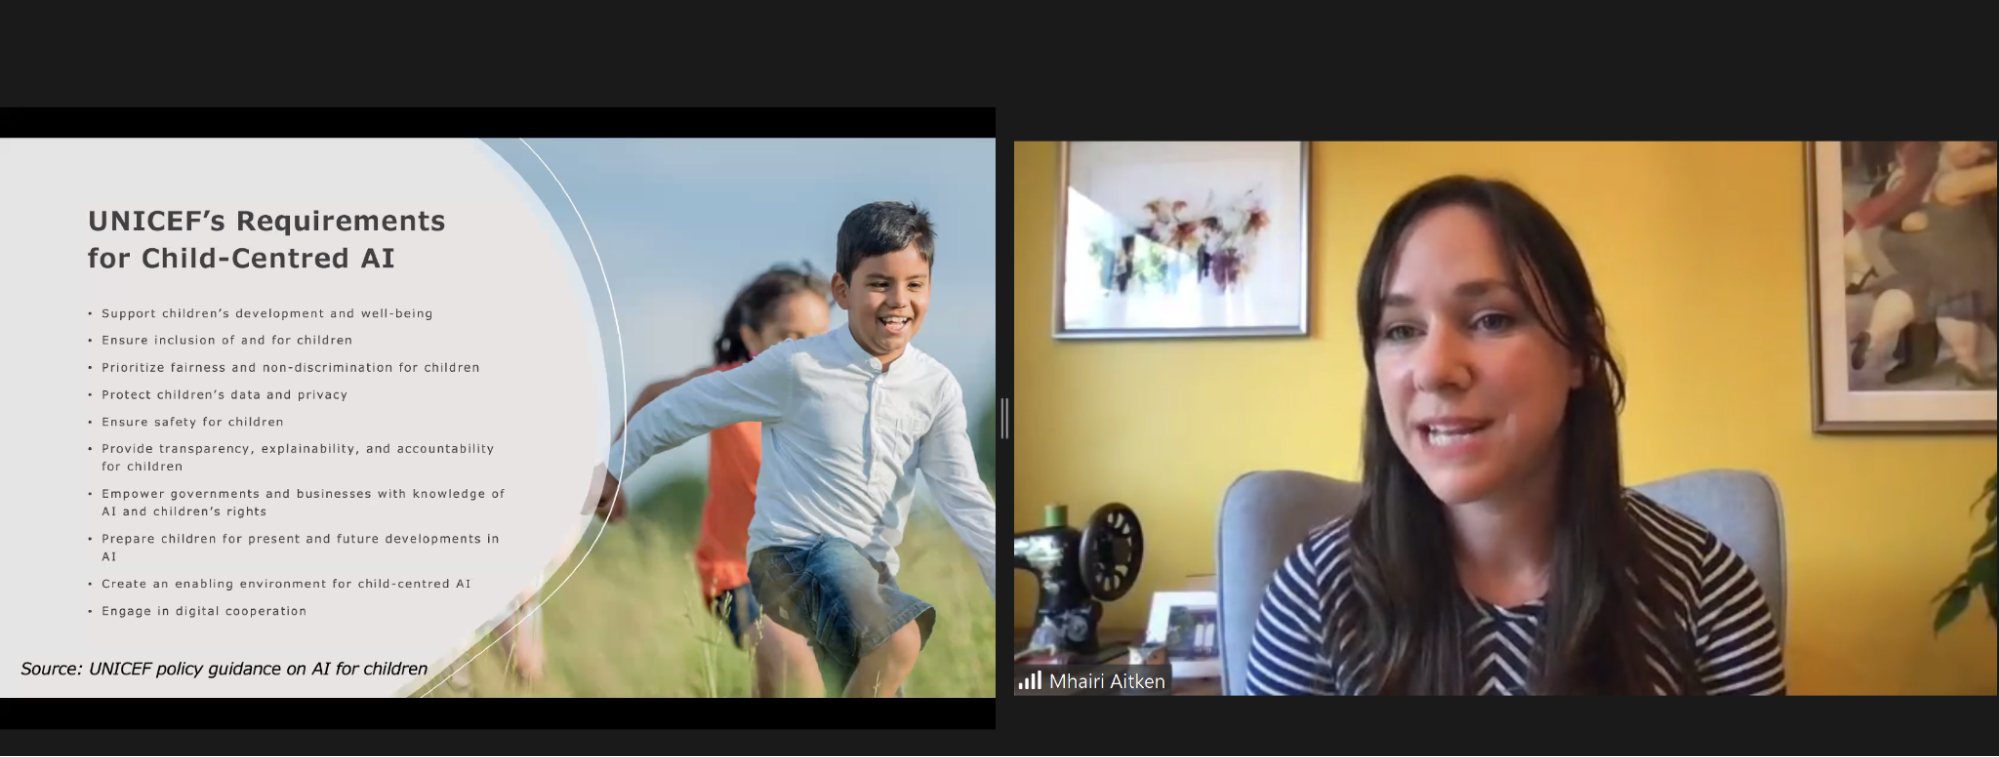Tag Archives: machine learning

Using Radar to Read Body Language

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/03/using-radar-to-read-body-language.html

Yet another method of surveillance:

Radar can detect you moving closer to a computer and entering its personal space. This might mean the computer can then choose to perform certain actions, like booting up the screen without requiring you to press a button. This kind of interaction already exists in current Google Nest smart displays, though instead of radar, Google employs ultrasonic sound waves to measure a person’s distance from the device. When a Nest Hub notices you’re moving closer, it highlights current reminders, calendar events, or other important notifications.

Proximity alone isn’t enough. What if you just ended up walking past the machine and looking in a different direction? To solve this, Soli can capture greater subtleties in movements and gestures, such as body orientation, the pathway you might be taking, and the direction your head is facing — ­aided by machine learning algorithms that further refine the data. All this rich radar information helps it better guess if you are indeed about to start an interaction with the device, and what the type of engagement might be.

[…]

The ATAP team chose to use radar because it’s one of the more privacy-friendly methods of gathering rich spatial data. (It also has really low latency, works in the dark, and external factors like sound or temperature don’t affect it.) Unlike a camera, radar doesn’t capture and store distinguishable images of your body, your face, or other means of identification. “It’s more like an advanced motion sensor,” Giusti says. Soli has a detectable range of around 9 feet­ — less than most cameras­ — but multiple gadgets in your home with the Soli sensor could effectively blanket your space and create an effective mesh network for tracking your whereabouts in a home.

“Privacy-friendly” is a relative term.

These technologies are coming. They’re going to be an essential part of the Internet of Things.

Bias in the machine: How can we address gender bias in AI?

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/gender-bias-in-ai-machine-learning-biased-data/

At the Raspberry Pi Foundation, we’ve been thinking about questions relating to artificial intelligence (AI) education and data science education for several months now, inviting experts to share their perspectives in a series of very well-attended seminars. At the same time, we’ve been running a programme of research trials to find out what interventions in school might successfully improve gender balance in computing. We’re learning a lot, and one primary lesson is that these topics are not discrete: there are relationships between them.

We can’t talk about AI education — or computer science education more generally — without considering the context in which we deliver it, and the societal issues surrounding computing, AI, and data. For this International Women’s Day, I’m writing about the intersection of AI and gender, particularly with respect to gender bias in machine learning.

The quest for gender equality

Gender inequality is everywhere, and researchers, activists, and initiatives, and governments themselves, have struggled since the 1960s to tackle it. As women and girls around the world continue to suffer from discrimination, the United Nations has pledged, in its Sustainable Development Goals, to achieve gender equality and to empower all women and girls.

While progress has been made, new developments in technology may be threatening to undo this. As Susan Leahy, a machine learning researcher from the Insight Centre for Data Analytics, puts it:

Artificial intelligence is increasingly influencing the opinions and behaviour of people in everyday life. However, the over-representation of men in the design of these technologies could quietly undo decades of advances in gender equality.

Susan Leavy, 2018 [1]

Gender-biased data

In her 2019 award-winning book Invisible Women: Exploring Data Bias in a World Designed for Men [2], Caroline Ceriado Perez discusses the effects of gender-biased data. She describes, for example, how the designs of cities, workplaces, smartphones, and even crash test dummies are all based on data gathered from men. She also discusses that medical research has historically been conducted by men, on male bodies.

Looking at this problem from a different angle, researcher Mayra Buvinic and her colleagues highlight that in most countries of the world, there are no sources of data that capture the differences between male and female participation in civil society organisations, or in local advisory or decision making bodies [3]. A lack of data about girls and women will surely impact decision making negatively. 

Bias in machine learning

Machine learning (ML) is a type of artificial intelligence technology that relies on vast datasets for training. ML is currently being use in various systems for automated decision making. Bias in datasets for training ML models can be caused in several ways. For example, datasets can be biased because they are incomplete or skewed (as is the case in datasets which lack data about women). Another example is that datasets can be biased because of the use of incorrect labels by people who annotate the data. Annotating data is necessary for supervised learning, where machine learning models are trained to categorise data into categories decided upon by people (e.g. pineapples and mangoes).

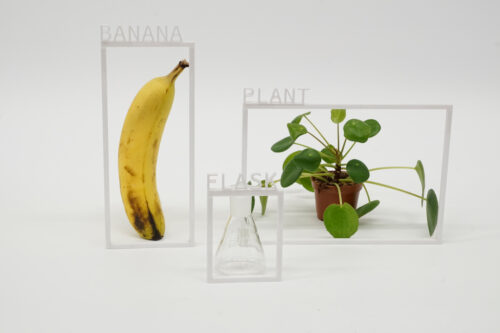
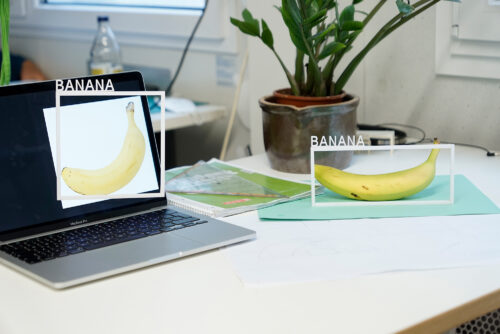
A banana, a glass flask, and a potted plant on a white surface. Each object is surrounded by a white rectangular frame with a label identifying the object.
Max Gruber / Better Images of AI / Banana / Plant / Flask / CC-BY 4.0

In order for a machine learning model to categorise new data appropriately, it needs to be trained with data that is gathered from everyone, and is, in the case of supervised learning, annotated without bias. Failing to do this creates a biased ML model. Bias has been demonstrated in different types of AI systems that have been released as products. For example:

Facial recognition: AI researcher Joy Buolamwini discovered that existing AI facial recognition systems do not identify dark-skinned and female faces accurately. Her discovery, and her work to push for the first-ever piece of legislation in the USA to govern against bias in the algorithms that impact our lives, is narrated in the 2020 documentary Coded Bias

Natural language processing: Imagine an AI system that is tasked with filling in the missing word in “Man is to king as woman is to X” comes up with “queen”. But what if the system completes “Man is to software developer as woman is to X” with “secretary” or some other word that reflects stereotypical views of gender and careers? AI models called word embeddings learn by identifying patterns in huge collections of texts. In addition to the structural patterns of the text language, word embeddings learn human biases expressed in the texts. You can read more about this issue in this Brookings Institute report

Not noticing

There is much debate about the level of bias in systems using artificial intelligence, and some AI researchers worry that this will cause distrust in machine learning systems. Thus, some scientists are keen to emphasise the breadth of their training data across the genders. However, other researchers point out that despite all good intentions, gender disparities are so entrenched in society that we literally are not aware of all of them. White and male dominance in our society may be so unconsciously prevalent that we don’t notice all its effects.

Three women discuss something while looking at a laptop screen.

As sociologist Pierre Bourdieu famously asserted in 1977: “What is essential goes without saying because it comes without saying: the tradition is silent, not least about itself as a tradition.” [4]. This view holds that people’s experiences are deeply, or completely, shaped by social conventions, even those conventions that are biased. That means we cannot be sure we have accounted for all disparities when collecting data.

What is being done in the AI sector to address bias?

Developers and researchers of AI systems have been trying to establish rules for how to avoid bias in AI models. An example rule set is given in an article in the Harvard Business Review, which describes the fact that speech recognition systems originally performed poorly for female speakers as opposed to male ones, because systems analysed and modelled speech for taller speakers with longer vocal cords and lower-pitched voices (typically men).

A women looks at a computer screen.

The article recommends four ways for people who work in machine learning to try to avoid gender bias:

  • Ensure diversity in the training data (in the example from the article, including as many female audio samples as male ones)
  • Ensure that a diverse group of people labels the training data
  • Measure the accuracy of a ML model separately for different demographic categories to check whether the model is biased against some demographic categories
  • Establish techniques to encourage ML models towards unbiased results

What can everybody else do?

The above points can help people in the AI industry, which is of course important — but what about the rest of us? It’s important to raise awareness of the issues around gender data bias and AI lest we find out too late that we are reintroducing gender inequalities we have fought so hard to remove. Awareness is a good start, and some other suggestions, drawn out from others’ work in this area are:

Improve the gender balance in the AI workforce

Having more women in AI and data science, particularly in both technical and leadership roles, will help to reduce gender bias. A 2020 report by the World Economic Forum (WEF) on gender parity found that women account for only 26% of data and AI positions in the workforce. The WEF suggests five ways in which the AI workforce gender balance could be addressed:

  1. Support STEM education
  2. Showcase female AI trailblazers
  3. Mentor women for leadership roles
  4. Create equal opportunities
  5. Ensure a gender-equal reward system

Ensure the collection of and access to high-quality and up-to-date gender data

We need high-quality dataset on women and girls, with good coverage, including country coverage. Data needs to be comparable across countries in terms of concepts, definitions, and measures. Data should have both complexity and granularity, so it can be cross-tabulated and disaggregated, following the recommendations from the Data2x project on mapping gender data gaps.

A woman works at a multi-screen computer setup on a desk.

Educate young people about AI

At the Raspberry Pi Foundation we believe that introducing some of the potential (positive and negative) impacts of AI systems to young people through their school education may help to build awareness and understanding at a young age. The jury is out on what exactly to teach in AI education, and how to teach it. But we think educating young people about new and future technologies can help them to see AI-related work opportunities as being open to all, and to develop critical and ethical thinking.

Three teenage girls at a laptop

In our AI education seminars we heard a number of perspectives on this topic, and you can revisit the videos, presentation slides, and blog posts. We’ve also been curating a list of resources that can help to further AI education — although there is a long way to go until we understand this area fully. 

We’d love to hear your thoughts on this topic.


References

[1] Leavy, S. (2018). Gender bias in artificial intelligence: The need for diversity and gender theory in machine learning. Proceedings of the 1st International Workshop on Gender Equality in Software Engineering, 14–16.

[2] Perez, C. C. (2019). Invisible Women: Exploring Data Bias in a World Designed for Men. Random House.

[3] Buvinic M., Levine R. (2016). Closing the gender data gap. Significance 13(2):34–37 

[4] Bourdieu, P. (1977). Outline of a Theory of Practice (No. 16). Cambridge University Press. (p.167)

The post Bias in the machine: How can we address gender bias in AI? appeared first on Raspberry Pi.

Leveraging machine learning to find security vulnerabilities

Post Syndicated from Tiferet Gazit original https://github.blog/2022-02-17-leveraging-machine-learning-find-security-vulnerabilities/

GitHub code scanning now uses machine learning (ML) to alert developers to potential security vulnerabilities in their code.

If you want to set up your repositories to surface more alerts using our new ML technology, get started here. Read on for a behind-the-scenes peek into the ML framework powering this new technology!

Detecting vulnerable code

Code security vulnerabilities can allow malicious actors to manipulate software into behaving in unintended and harmful ways. The best way to prevent such attacks is to detect and fix vulnerable code before it can be exploited. GitHub’s code scanning capabilities leverage the CodeQL analysis engine to find security vulnerabilities in source code and surface alerts in pull requests – before the vulnerable code gets merged and released.

To detect vulnerabilities in a repository, the CodeQL engine first builds a database that encodes a special relational representation of the code. On that database we can then execute a series of CodeQL queries, each of which is designed to find a particular type of security problem.

Many vulnerabilities are caused by a single repeating pattern: untrusted user data is not sanitized and is subsequently accidentally used in an unsafe way. For example, SQL injection is caused by using untrusted user data in a SQL query, and cross-site scripting occurs as a result of untrusted user data being written to a web page. To detect situations in which unsafe user data ends up in a dangerous place, CodeQL queries encapsulate knowledge of a large number of potential sources of user data (for example, web frameworks), as well as potentially risky sinks (such as libraries for executing SQL queries). Members of the security community, alongside security experts at GitHub, continually expand and improve these queries to model additional common libraries and known patterns. Manual modeling, however, can be time-consuming, and there will always be a long tail of less-common libraries and private code that we won’t be able to model manually. This is where machine learning comes in.

We use examples surfaced by the manual models to train deep learning neural networks that can determine whether a code snippet comprises a potentially risky sink.

As a result, we can uncover security vulnerabilities even when they arise from the use of a library we have never seen before. For example, we can detect SQL injection vulnerabilities in the context of lesser-known or closed-source database abstraction libraries.

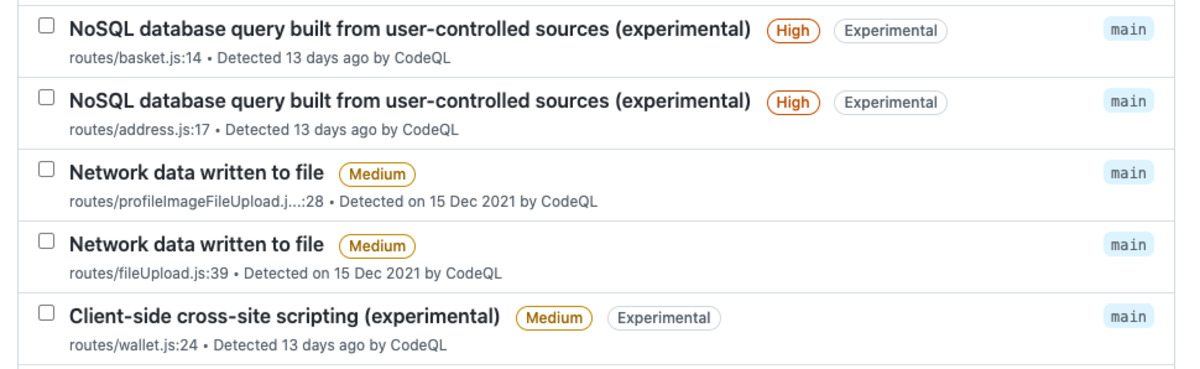
Screenshot of alerts with "experimental" label
ML-powered queries generate alerts that are marked with the “Experimental” label

Building a training set

We need to train ML models to recognize vulnerable code. While we have experimented some with unsupervised learning, unsurprisingly we found that supervised learning works better. But it comes at a cost! Asking code security experts to manually label millions of code snippets as safe or vulnerable is clearly untenable. So where do we get the data?

The manually written CodeQL queries already embody the expertise of the many security experts who wrote and refined them. We leverage these manual queries as ground-truth oracles, to label examples we then use to train our models. Each sink detected by such a query serves as a positive example in the training set. Since the vast majority of code snippets do not contain vulnerabilities, snippets not detected by the manual models can be regarded as negative examples. We make up for the inherent noise in this inferred labeling with volume. We extract tens of millions of snippets from over a hundred thousand public repositories, run the CodeQL queries on them, and label each as a positive or negative example for each query. This becomes the training set for a machine learning model that can classify code snippets as vulnerable or not.

Of course, we don’t want to train a model that will simply reproduce the manual modeling; we want to train a model that will predict new vulnerabilities that weren’t captured by manual modeling. In effect, we want the ML algorithm to improve on the current version of the manual query in much the same way that the current version improves on older, less-comprehensive versions. To see if we can do this, we actually construct all our training data from an older version of the query that detects fewer vulnerabilities. We then apply the trained model to new repositories it wasn’t trained on. We measure how well we recover the alerts detected by the latest manual query but missed by the older version of the query. This allows us to simulate the ability of a model trained with the current version of the query to recover alerts missed by this current manual model.

Features and modeling

Given a large training set of code snippets labeled as positive or negative examples for each query, we extract features for each snippet and train a deep learning model to classify new examples.

Rather than treating each code snippet simply as a string of words or characters and applying standard natural language processing (NLP) techniques naively to classify these strings, we leverage the power of CodeQL to access a wealth of information about the underlying source code. We use this information to produce a rich set of highly informative features for each code snippet.

One of the main advantages of deep learning models is their ability to combine information from a large set of features to create higher-level features and discover patterns that aren’t obvious to humans. In partnership with security and programming-language experts at GitHub, we use CodeQL to extract the information an expert might examine to inform a decision, such as the entire enclosing function body for a snippet that sits within a function, or the access path and API name. We don’t have to limit ourselves to features a human would find informative, however. We can include features whose usefulness is unknown, or features that can be useful in some instances but not all, such as the argument index for a code snippet that’s an argument to a function. Such features may contain patterns that aren’t apparent to humans, but that the neural network can detect. We therefore let the machine learning model decide whether or how to use all these features, and how to combine them to make the best decision for each snippet.

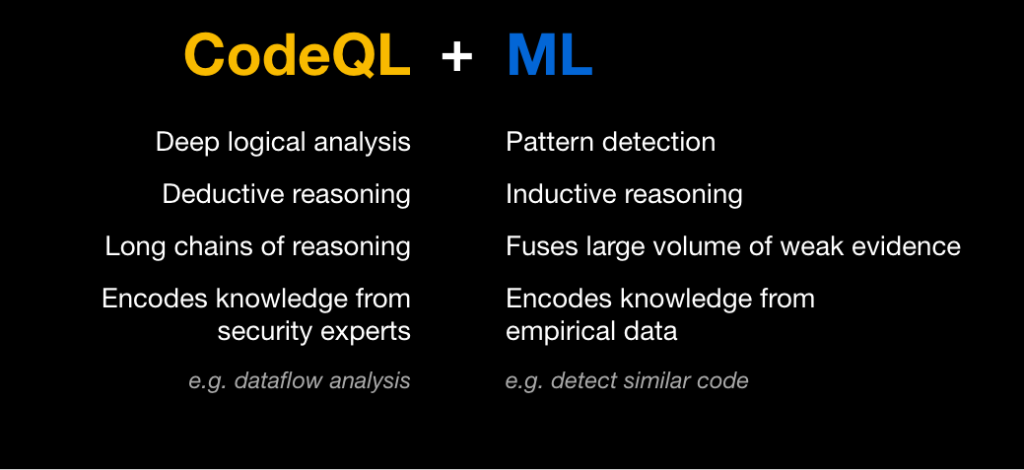
Slide with text: CodeQL: Deep logical analysis, Deductive reasoning Long chains of reasoning, Encodes knowledge from security experts ML: Pattern detection, Inductive reasoning, Fuses large volume of weak evidence, Encodes knowledge from empirical data.

Once we’ve extracted a rich set of potentially interesting features for each example, we tokenize and sub-tokenize them as is commonly done in NLP applications, with some modifications to capture characteristics specific to code syntax. We generate a vocabulary from the training data and feed lists of indices into the vocabulary into a fairly simple deep learning classifier, with a few layers of feature-by-feature processing followed by concatenation across features and a few layers of combined processing. The output is the probability that the current sample is a vulnerability for each query type.

Due to the scale of our offline data labeling, feature extraction, and training pipelines, we leverage cloud compute, including GPUs for model training. At inference time, however, no GPU is needed.

Inference on a repository

Once we have our trained machine learning model, we use it to classify new code snippets and detect likely vulnerabilities for each query. When ML-generated alerts are enabled by repository owners, CodeQL computes the source code features for the code snippets in that codebase and feeds them into the classifier model. The framework gets back the probability that a given code snippet represents a vulnerability, and uses this probability to surface likely new alerts.

Diagram showing how code snippets feed into CodeQL and the classifier model.

The full process runs on the same standard GitHub Action runners that are used by code scanning more generally, and it’s transparent to the user other than some increased runtime on large repositories. When the code scanning is complete, users can see the ML-generated alerts along with the alerts surfaced by the manual queries, with the “Experimental” label allowing them to filter ML-generated alerts in or out.

Does it work?

When evaluating ML-generated alerts, we consider only new alerts that were not flagged by the manual queries. True positives are the correct alerts that were missed by the manual queries; false positives are the incorrect new alerts generated by the ML model.

To measure metrics at scale, we use the experimental setup described above, in which the labels in the training set are determined using an older version of each manual query. We then test the model on repositories that were not included in the training set, and we measure its ability to recover the alerts detected by the current manual query but missed by the older one. Our metrics vary by query, but on average we measure a recall of approximately 80% with a precision of approximately 60%.

We’re currently extending ML-generated alerts to more JavaScript and Typescript security queries, as well as working to improve both their performance and their runtime. Our future plans include expansion to more programming languages, as well as generalizations that will allow us to capture even more vulnerabilities.

Run the “Experimental” queries if you want to uncover more potential security vulnerabilities in your codebase. The more the community engages with our alerts and provides feedback, the better we can make our algorithms, so please consider giving them a try!

Let’s Architect! Architecting for Machine Learning

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/architecting-for-machine-learning/

Though it seems like something out of a sci-fi movie, machine learning (ML) is part of our day-to-day lives. So often, in fact, that we may not always notice it. For example, social networks and mobile applications use ML to assess user patterns and interactions to deliver a more personalized experience.

However, AWS services provide many options for the integration of ML. In this post, we will show you some use cases that can enhance your platforms and integrate ML into your production systems.

Dynamic A/B testing for machine learning models with Amazon SageMaker MLOps projects

Performing A/B testing on production traffic to compare a new ML model with the old model is a recommended step after offline evaluation.

This blog post explains how A/B testing works and how it can be combined with multi-armed bandit testing to gradually send traffic to the more effective variants during the experiment. It will teach you how to build it with AWS Cloud Development Kit (AWS CDK), architect your system for MLOps, and automate the deployment of the solutions for A/B testing.

This diagram shows the iterative process to analyze the performance of ML models in online and offline scenarios.

This diagram shows the iterative process to analyze the performance of ML models in online and offline scenarios

Enhance your machine learning development by using a modular architecture with Amazon SageMaker projects

Modularity is a key characteristic for modern applications. You can modularize code, infrastructure, and even architecture.

A modular architecture provides an architecture and framework that allows each development role to work on their own part of the system, and hide the complexity of integration, security, and environment configuration. This blog post provides an approach to building a modular ML workload that is easy to evolve and maintain across multiple teams.

A modular architecture allows you to easily assemble different parts of the system and replace them when needed

A modular architecture allows you to easily assemble different parts of the system and replace them when needed

Automate model retraining with Amazon SageMaker Pipelines when drift is detected

The accuracy of ML models can deteriorate over time because of model drift or concept drift. This is a common challenge when deploying your models to production. Have you ever experienced it? How would you architect a solution to address this challenge?

Without metrics and automated actions, maintaining ML models in production can be overwhelming. This blog post shows you how to design an MLOps pipeline for model monitoring to detect concept drift. You can then expand the solution to automatically launch a new training job after the drift was detected to learn from the new samples, update the model, and take into account the changes in the data distribution.

Concept drift happens when there is a shift in the distribution. In this case, the distribution of the newly collected data (in blue) starts differing from the baseline distribution (in green)

Concept drift happens when there is a shift in the distribution. In this case, the distribution of the newly collected data (in blue) starts differing from the baseline distribution (in green)

Architect and build the full machine learning lifecycle with AWS: An end-to-end Amazon SageMaker demo

Moving from experimentation to production forces teams to move fast and automate their operations. Adopting scalable solutions for MLOps is a fundamental step to successfully create production-oriented ML processes.

This blog post provides an extended walkthrough of the ML lifecycle and explains how to optimize the process using Amazon SageMaker. Starting from data ingestion and exploration, you will see how to train your models and deploy them for inference. Then, you’ll make your operations consistent and scalable by architecting automated pipelines. This post offers a fraud detection use case so you can see how all of this can be used to put ML in production.

The ML lifecycle involves three macro steps: data preparation, train and tuning, and deployment with continuous monitoring.

The ML lifecycle involves three macro steps: data preparation, train and tuning, and deployment with continuous monitoring

See you next time!

Thanks for reading! We’ll see you in a couple of weeks when we discuss how to secure your workloads in AWS.

Looking for more architecture content? AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Other posts in this series

The AI4K12 project: Big ideas for AI education

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/ai-education-ai4k12-big-ideas-ai-thinking/

What is AI thinking? What concepts should we introduce to young people related to AI, including machine learning (ML), and data science? Should we teach with a glass-box or an opaque-box approach? These are the questions we’ve been grappling with since we started our online research seminar series on AI education at the Raspberry Pi Foundation, co-hosted with The Alan Turing Institute.

Over the past few months, we’d already heard from researchers from the UK, Germany, and Finland. This month we virtually travelled to the USA, to hear from Prof. Dave Touretzky (Carnegie Mellon University) and Prof. Fred G. Martin (University of Massachusetts Lowell), who have pioneered the influential AI4K12 project together with their colleagues Deborah Seehorn and Christina Gardner-McLure.

The AI4K12 project

The AI4K12 project focuses on teaching AI in K-12 in the US. The AI4K12 team have aligned their vision for AI education to the CSTA standards for computer science education. These Standards, published in 2017, describe what should be taught in US schools across the discipline of computer science, but they say very little about AI. This was the stimulus for starting the AI4K12 initiative in 2018. A number of members of the AI4K12 working group are practitioners in the classroom who’ve made a huge contribution in taking this project from ideas into the classroom.

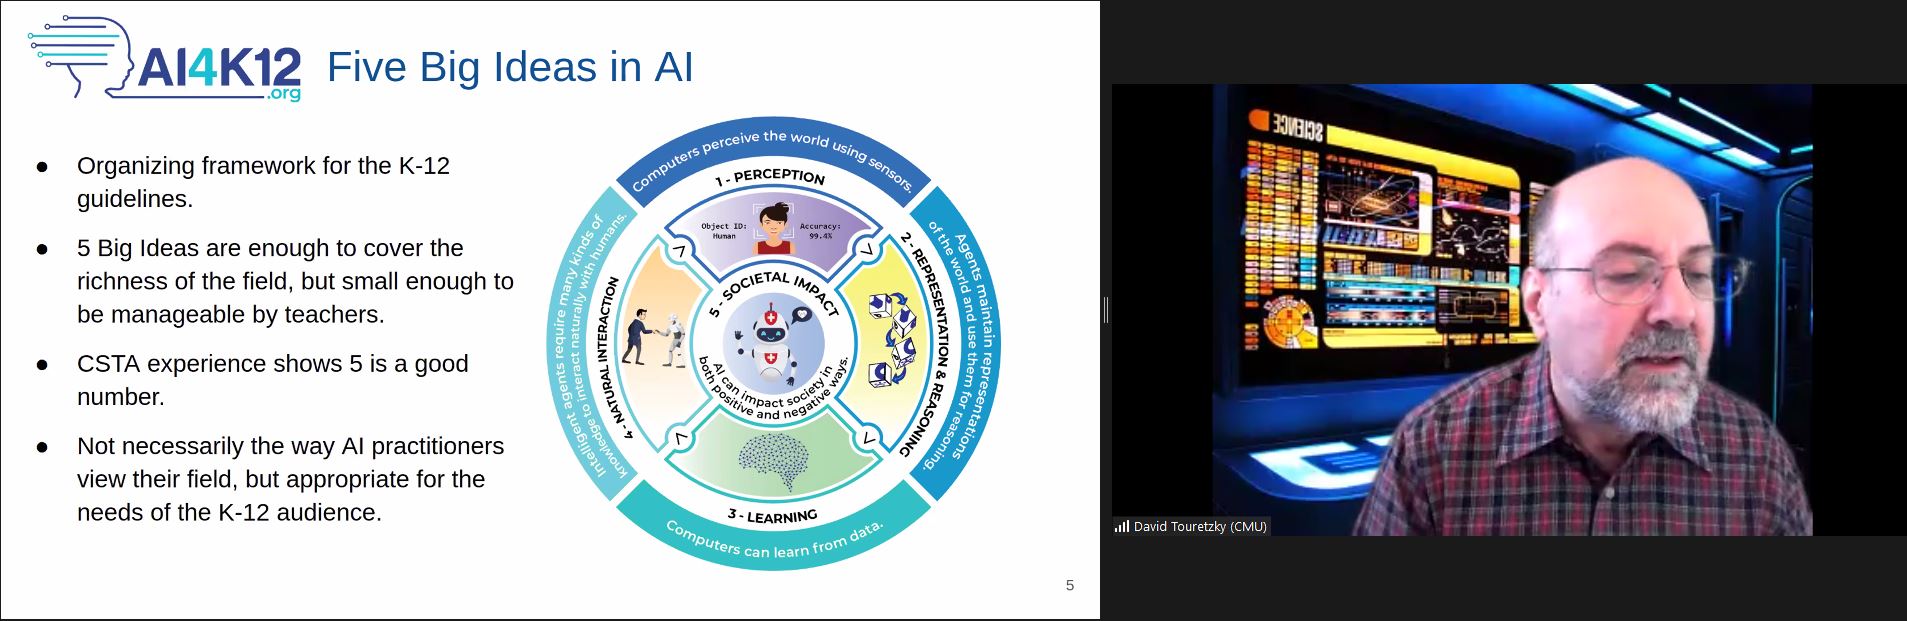
Dave Touretzky presents the five big ideas of the AI4K12 project at our online research seminar.
Dave gave us an overview of the AI4K12 project (click to enlarge)

The project has a number of goals. One is to develop a curated resource directory for K-12 teachers, and another to create a community of K-12 resource developers. On the AI4K12.org website, you can find links to many resources and sign up for their mailing list. I’ve been subscribed to this list for a while now, and fascinating discussions and resources have been shared. 

Five Big Ideas of AI4K12

If you’ve heard of AI4K12 before, it’s probably because of the Five Big Ideas the team has set out to encompass the AI field from the perspective of school-aged children. These ideas are: 

  1. Perception — the idea that computers perceive the world through sensing
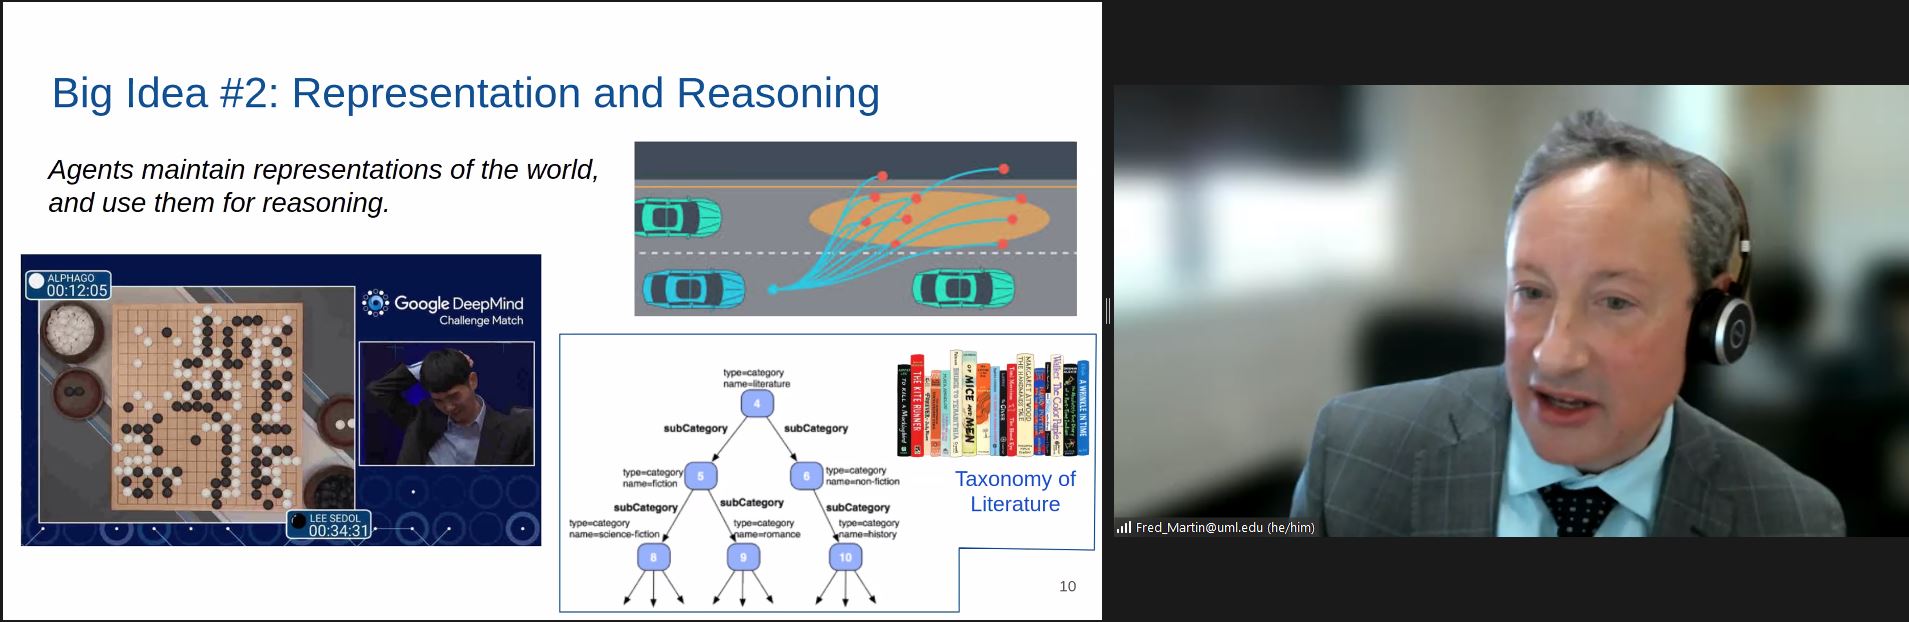
  2. Representation and reasoning — the idea that agents maintain representations of the world and use them for reasoning
  3. Learning — the idea that computers can learn from data
  4. Natural interaction — the idea that intelligent agents require many types of knowledge to interact naturally with humans
  5. Societal impact — the idea that artificial intelligence can impact society in both positive and negative ways

Sometimes we hear concerns that resources being developed to teach AI concepts to young people are narrowly focused on machine learning, particularly supervised learning for classification. It’s clear from the AI4K12 Five Big Ideas that the team’s definition of the AI field encompasses much more than one area of ML. Despite being developed for a US audience, I believe the description laid out in these five ideas is immensely useful to all educators, researchers, and policymakers around the world who are interested in AI education.

Fred Martin presents one of the five big ideas of the AI4K12 project at our online research seminar.
Fred explained how ‘representation and reasoning’ is a big idea in the AI field (click to enlarge)

During the seminar, Dave and Fred shared some great practical examples. Fred explained how the big ideas translate into learning outcomes at each of the four age groups (ages 5–8, 9–11, 12–14, 15–18). You can find out more about their examples in their presentation slides or the seminar recording (see below). 

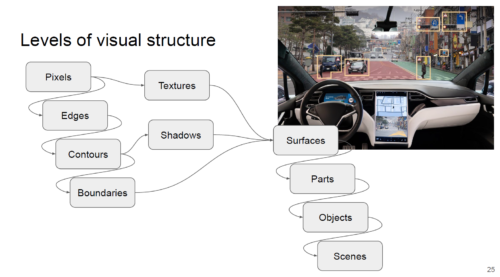
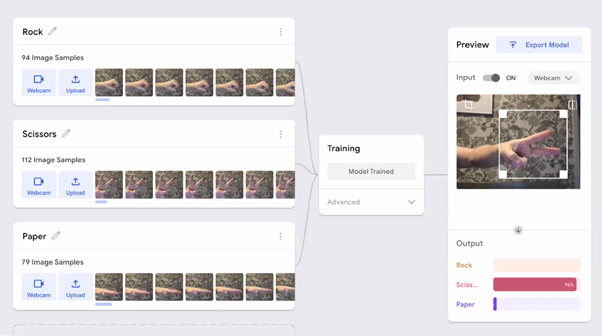
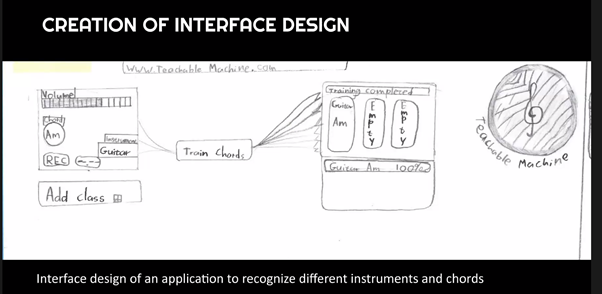
I was struck by how much the AI4K12 team has thought about progression — what you learn when, and in which sequence — which we do really need to understand well before we can start to teach AI in any formal way. For example, looking at how we might teach visual perception to young people, children might start when very young by using a tool such as Teachable Machine to understand that they can teach a computer to recognise what they want it to see, then move on to building an application using Scratch plugins or Calypso, and then to learning the different levels of visual structure and understanding the abstraction pipeline — the hierarchy of increasingly abstract things. Talking about visual perception, Fred used the example of self-driving cars and how they represent images.

A diagram of the levels of visual structure.
Fred used this slide to describe how young people might learn abstracted elements of visual structure

AI education with an age-appropriate, glass-box approach

Dave and Fred support teaching AI to children using a glass-box approach. By ‘glass-box approach’ we mean that we should give students information about how AI systems work, and show the inner workings, so to speak. The opposite would be a ‘opaque-box approach’, by which we mean showing students an AI system’s inputs and the outputs only to demonstrate what AI is capable of, without trying to teach any technical detail.

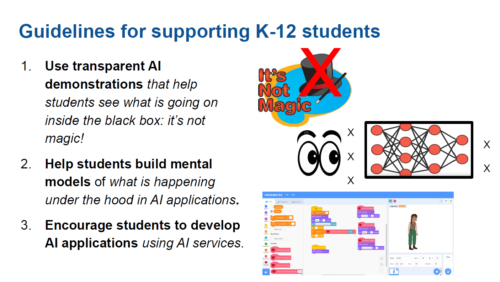
AI4K12 advice for educators supporting K-12 students: 1. Use transparent AI demonstrations. 2. Help students build mental models. 3. Encourage students to build AI applications.
AI4K12 teacher guidelines for AI education

Our speakers are keen for learners to understand, at an age-appropriate level, what is going on “inside” an AI system, not just what the system can do. They believe it’s important for young people to build mental models of how AI systems work, and that when the young people get older, they should be able to use their increasing knowledge and skills to develop their own AI applications. This aligns with the views of some of our previous seminar speakers, including Finnish researchers Matti Tedre and Henriikka Vartiainen, who presented at our seminar series in November

What is AI thinking?

Dave addressed the question of what AI thinking looks like in school. His approach was to start with computational thinking (he used the example of the Barefoot project’s description of computational thinking as a starting point) and describe AI thinking as an extension that includes the following skills:

  • Perception 
  • Reasoning
  • Representation
  • Machine learning
  • Language understanding
  • Autonomous robots

Dave described AI thinking as furthering the ideas of abstraction and algorithmic thinking commonly associated with computational thinking, stating that in the case of AI, computation actually is thinking. My own view is that to fully define AI thinking, we need to dig a bit deeper into, for example, what is involved in developing an understanding of perception and representation.

An image demonstrating that AI systems for object recognition may not distinguish between a real banana on a desk and the photo of a banana on a laptop screen.
Image: Max Gruber / Better Images of AI / Ceci n’est pas une banane / CC-BY 4.0

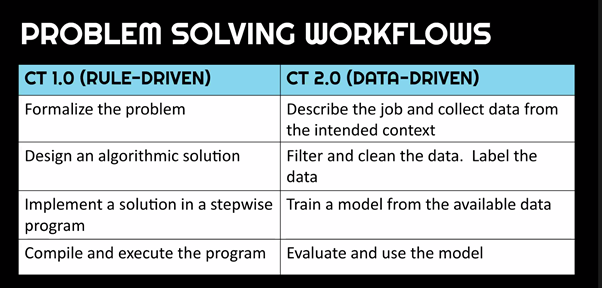
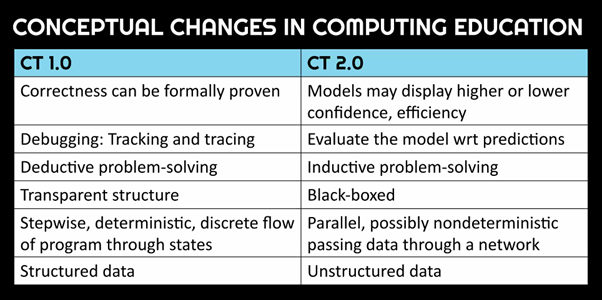
Thinking back to Matti Tedre and Henriikka Vartainen’s description of CT 2.0, which focuses only on the ‘Learning’ aspect of the AI4K12 Five Big Ideas, and on the distinct ways of thinking underlying data-driven programming and traditional programming, we can see some differences between how the two groups of researchers describe the thinking skills young people need in order to understand and develop AI systems. Tedre and Vartainen are working on a more finely granular description of ML thinking, which has the potential to impact the way we teach ML in school.

There is also another description of AI thinking. Back in 2020, Juan David Rodríguez García presented his system LearningML at one of our seminars. Juan David drew on a paper by Brummelen, Shen, and Patton, who extended Brennan and Resnick’s CT framework of concepts, practices, and perspectives, to include concepts such as classification, prediction, and generation, together with practices such as training, validating, and testing.

What I take from this is that there is much still to research and discuss in this area! It’s a real privilege to be able to hear from experts in the field and compare and contrast different standpoints and views.

Resources for AI education

The AI4K12 project has already made a massive contribution to the field of AI education, and we were delighted to hear that Dave, Fred, and their colleagues have just been awarded the AAAI/EAAI Outstanding Educator Award for 2022 for AI4K12.org. An amazing achievement! Particularly useful about this website is that it links to many resources, and that the Five Big Ideas give a framework for these resources.

Through our seminars series, we are developing our own list of AI education resources shared by seminar speakers or attendees, or developed by us. Please do take a look.

Join our next seminar

Through these seminars, we’re learning a lot about AI education and what it might look like in school, and we’re having great discussions during the Q&A section.

On Tues 1 February at 17:00–18:30 GMT, we’ll hear from Tara Chklovski, who will talk about AI education in the context of the Sustainable Development Goals. To participate, click the button below to sign up, and we will send you information about joining. I really hope you’ll be there for this seminar!

The schedule of our upcoming seminars is online. You can also (re)visit past seminars and recordings on the blog.

The post The AI4K12 project: Big ideas for AI education appeared first on Raspberry Pi.

Being Naughty to See Who Was Nice: Machine Learning Attacks on Santa’s List

Post Syndicated from Erick Galinkin original https://blog.rapid7.com/2022/01/14/being-naughty-to-see-who-was-nice-machine-learning-attacks-on-santas-list/

Being Naughty to See Who Was Nice: Machine Learning Attacks on Santa’s List

Editor’s note: We had planned to publish our Hacky Holidays blog series throughout December 2021 – but then Log4Shell happened, and we dropped everything to focus on this major vulnerability that impacted the entire cybersecurity community worldwide. Now that it’s 2022, we’re feeling in need of some holiday cheer, and we hope you’re still in the spirit of the season, too. Throughout January, we’ll be publishing Hacky Holidays content (with a few tweaks, of course) to give the new year a festive start. So, grab an eggnog latte, line up the carols on Spotify, and let’s pick up where we left off.

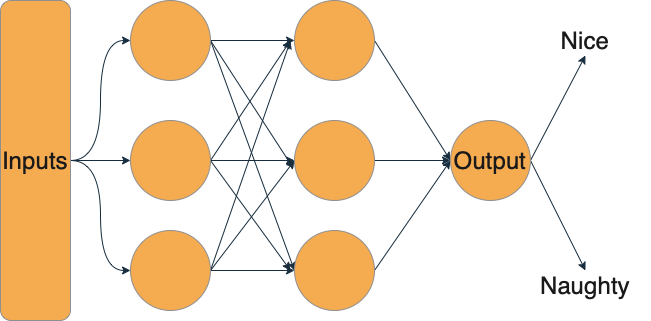
Santa’s task of making the nice and naughty list has gotten a lot harder over time. According to estimates, there are around 2.2 billion children in the world. That’s a lot of children to make a list of, much less check it twice! So like many organizations with big data problems, Santa has turned to machine learning to help him solve the issue and built a classifier using historical naughty and nice lists. This makes it easy to let the algorithm decide whether they’ll be getting the gifts they’ve asked for or a lump of coal.

Being Naughty to See Who Was Nice: Machine Learning Attacks on Santa’s List

Santa’s lists have long been a jealously guarded secret. After all, being on the naughty list can turn one into a social pariah. Thus, Santa has very carefully protected his training data — it’s locked up tight. Santa has, however, made his model’s API available to anyone who wants it. That way, a parent can check whether their child is on the nice or naughty list.

Santa, being a just and equitable person, has already asked his data elves to tackle issues of algorithmic bias. Unfortunately, these data elves have overlooked some issues in machine learning security. Specifically, the issues of membership inference and model inversion.

Membership inference attacks

Membership inference is a class of machine learning attacks that allows a naughty attacker to query a model and ask, in effect, “Was this example in your training data?” Using the techniques of Salem et al. or a tool like PrivacyRaven, an attacker can train a model that figures out whether or not a model has seen an example before.

Being Naughty to See Who Was Nice: Machine Learning Attacks on Santa’s List

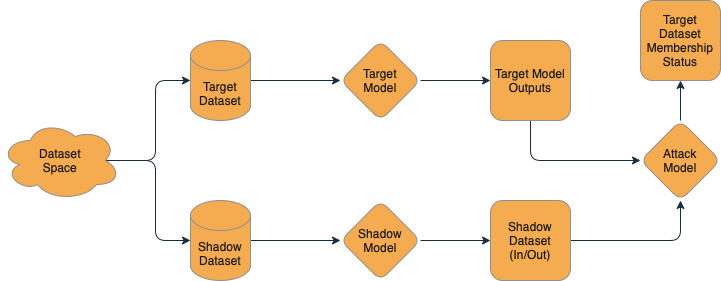
From a technical perspective, we know that there is some amount of memorization in models, and so when they make their predictions, they are more likely to be confident on items that they have seen before — in some ways, “memorizing” examples that have already been seen. We can then create a dataset for our “shadow” model — a model that approximates Santa’s nice/naughty system, trained on data that we’ve collected and labeled ourselves.

We can then take the training data and label the outputs of this model with a “True” value — it was in the training dataset. Then, we can run some additional data through the model for inference and collect the outputs and label it with a “False” value — it was not in the training dataset. It doesn’t matter if these in-training and out-of-training data points are nice or naughty — just that we know if they were in the “shadow” training dataset or not. Using this “shadow” dataset, we train a simple model to answer the yes or no question: “Was this in the training data?” Then, we can turn our naughty algorithm against Santa’s model — “Dear Santa, was this in your training dataset?” This lets us take real inputs to Santa’s model and find out if the model was trained on that data — effectively letting us de-anonymize the historical nice and naughty lists!

Model inversion

Now being able to take some inputs and de-anonymize them is fun, but what if we could get the model to just tell us all its secrets? That’s where model inversion comes in! Fredrikson et al. proposed model inversion in 2015 and really opened up the realm of possibilities for extracting data from models. Model inversion seeks to take a model and, as the name implies, turn the output we can see into the training inputs. Today, extracting data from models has been done at scale by the likes of Carlini et al., who have managed to extract data from large language models like GPT-2.

Being Naughty to See Who Was Nice: Machine Learning Attacks on Santa’s List

In model inversion, we aim to extract memorized training data from the model. This is easier with generative models than with classifiers, but a classifier can be used as part of a larger model called a Generative Adversarial Network (GAN). We then sample the generator, requesting text or images from the model. Then, we use the membership inference attack mentioned above to identify outputs that are more likely to belong to the training set. We can iterate this process over and over to generate progressively more training set-like outputs. In time, this will provide us with memorized training data.

Note that model inversion is a much heavier lift than membership inference and can’t be done against all models all the time — but for models like Santa’s, where the training data is so sensitive, it’s worth considering how much we might expose! To date, model inversion has only been conducted in lab settings on models for text generation and image classification, so whether or not it could work on a binary classifier like Santa’s list remains an open question.

Mitigating model mayhem

Now, if you’re on the other side of this equation and want to help Santa secure his models, there are a few things we can do. First and foremost, we want to log, log, log! In order to carry out the attacks, the model — or a very good approximation — needs to be available to the attacker. If you see a suspicious number of queries, you can filter IP addresses or rate limit. Additionally, limiting the return values to merely “naughty” or “nice” instead of returning the probabilities can make both attacks more difficult.

For extremely sensitive applications, the use of differential privacy or optimizing with DPSGD can also make it much more difficult for attackers to carry out their attacks, but be aware that these techniques come with some accuracy loss. As a result, you may end up with some nice children on the naughty list and a naughty hacker on your nice list.

Santa making his list into a model will save him a whole lot of time, but if he’s not careful about how the model can be queried, it could also lead to some less-than-jolly times for his data. Membership inference and model inversion are two types of privacy-related attacks that models like this may be susceptible to. As a best practice, Santa should:

  • Log information about queries like:
    • IP address
    • Input value
    • Output value
    • Time
  • Consider differentially private model training
  • Limit API access
  • Limit the information returned from the model to label-only

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

More Hacky Holidays blogs

What’s new in Zabbix 6.0 LTS by Artūrs Lontons / Zabbix Summit Online 2021

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/whats-new-in-zabbix-6-0-lts-by-arturs-lontons-zabbix-summit-online-2021/17761/

Zabbix 6.0 LTS comes packed with many new enterprise-level features and improvements. Join Artūrs Lontons and take a look at some of the major features that will be available with the release of Zabbix 6.0 LTS.

The full recording of the speech is available on the official Zabbix Youtube channel.

If we look at the Zabbix roadmap and Zabbix 6.0 LTS release in particular, we can see that one of the main focuses of Zabbix development is releasing features that solve many complex enterprise-grade problems and use cases. Zabbix 6.0 LTS aims to:

  • Solve enterprise-level security and redundancy requirements
  • Improve performance for large Zabbix instances
  • Provide additional value to different types of Zabbix users – DevOPS and ITOps teams, Business process owner, Managers
  • Continue to extend Zabbix monitoring and data collection capabilities
  • Provide continued delivery of official integrations with 3rd party systems

Let’s take a look at the specific Zabbix 6.0 LTS features that can guide us towards achieving these goals.

Zabbix server High Availability cluster

With the release of Zabbix 6.0 LTS, Zabbix administrators will now have the ability to deploy Zabbix server HA cluster out-of-the-box. No additional tools are required to achieve this.

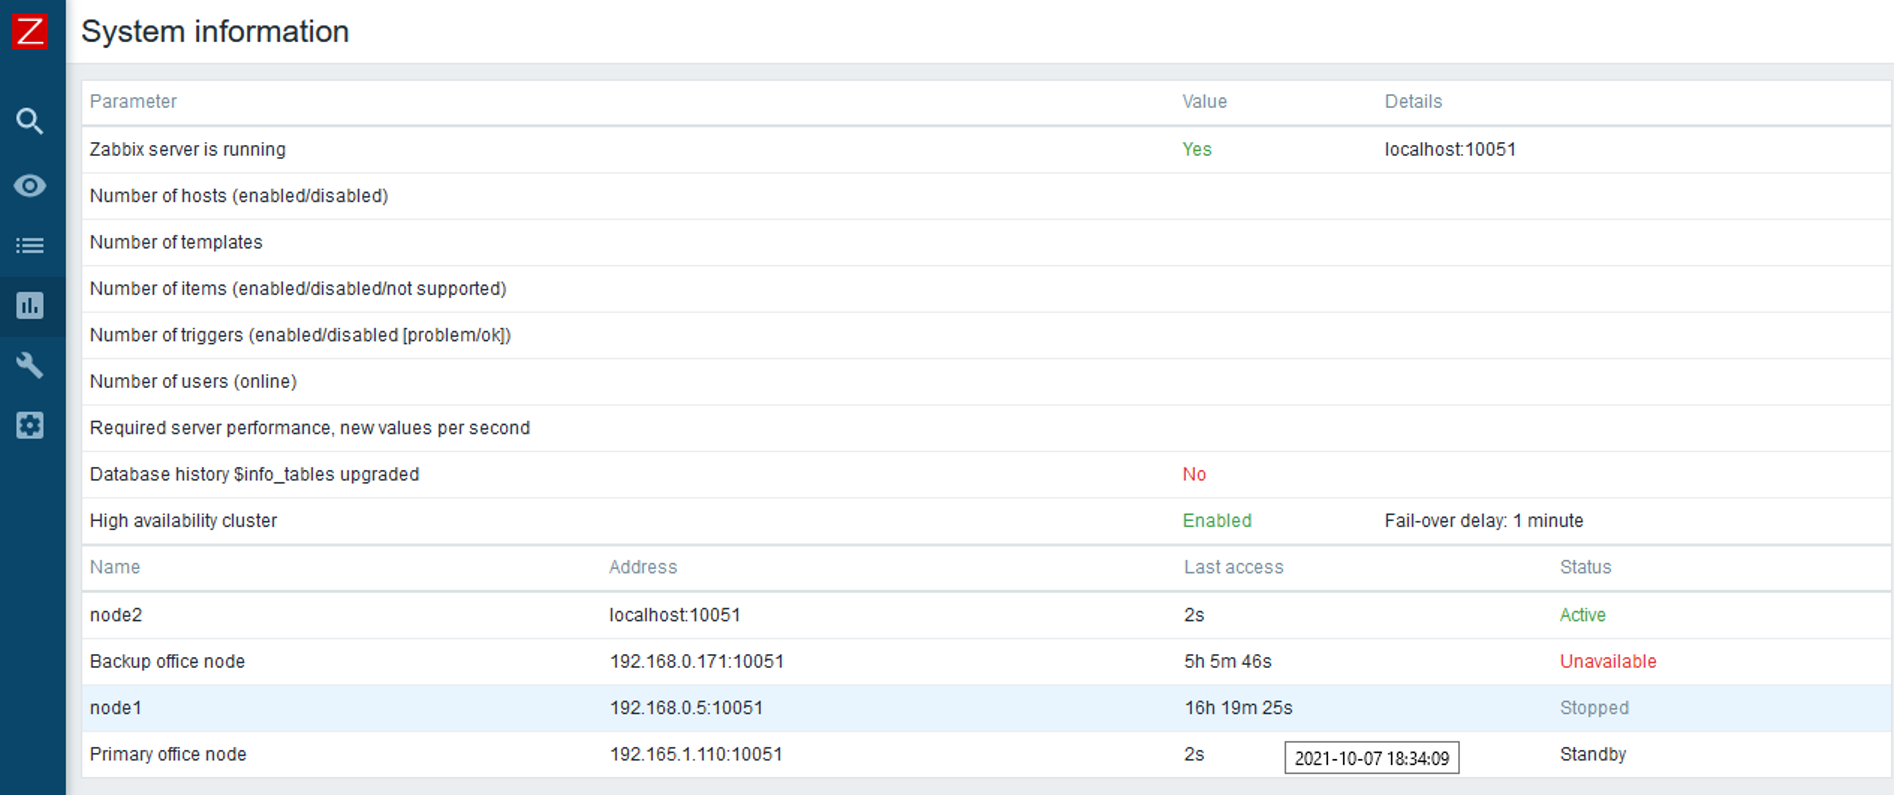
Zabbix server HA cluster supports an unlimited number of Zabbix server nodes. All nodes will use the same database backend – this is where the status of all nodes will be stored in the ha_node table. Nodes will report their status every 5 seconds by updating the corresponding record in the ha_node table.

To enable High availability, you will first have to define a new parameter in the Zabbix server configuration file: HANodeName

  • Empty by default
  • This parameter should contain an arbitrary name of the HA node
  • Providing value to this parameter will enable Zabbix server cluster mode

Standby nodes monitor the last access time of the active node from the ha_node table.

  • If the difference between last access time and current time reaches the failover delay, the cluster fails over to the standby node
  • Failover operation is logged in the Zabbix server log

It is possible to define a custom failover delay – a time window after which an unreachable active node is considered lost and failover to one of the standby nodes takes place.

As for the Zabbix proxies, the Server parameter in the Zabbix proxy configuration file now supports multiple addresses separated by a semicolon. The proxy will attempt to connect to each of the nodes until it succeeds.

Other HA cluster related features:

  • New command-line options to check HA cluster status
  • hanode.get API method to obtain the list of HA nodes
  • The new internal check provides LLD information to discover Zabbix server HA nodes
  • HA Failover event logged in the Zabbix Audit log
  • Zabbix Frontend will automatically switch to the active Zabbix server node

You can find a more detailed look at the Zabbix Server HA cluster feature in the Zabbix Summit Online 2021 speech dedicated to the topic.

Business service monitoring

The Services section has received a complete redesign in Zabbix 6.0 LTS. Business Service Monitoring (BSM) enables Zabbix administrators to define services of varying complexity and monitor their status.

BSM provides added value in a multitude of use cases, where we wish to define and monitor services based on:

  • Server clusters
  • Services that utilize load balancing
  • Services that consist of a complex IT stack
  • Systems with redundant components in place
  • And more

Business Service monitoring has been designed with scalability in mind. Zabbix is capable of monitoring over 100k services on a single Zabbix instance.

For our Business Service example, we used a website, which depends on multiple components such as the network connection, DB backend, Application server, and more. We can see that the service status calculation is done by utilizing tags and deciding if the existing problems will affect the service based on the problem tags.

In Zabbix 6.0 LTS there are many ways how service status calculations can be performed. In case of a problem, the service state can be changed to:

  • The most critical problem severity, based on the child service problem severities
  • The most critical problem severity, based on the child service problem severities, only if all child services are in a problem state
  • The service is set to constantly be in an OK state

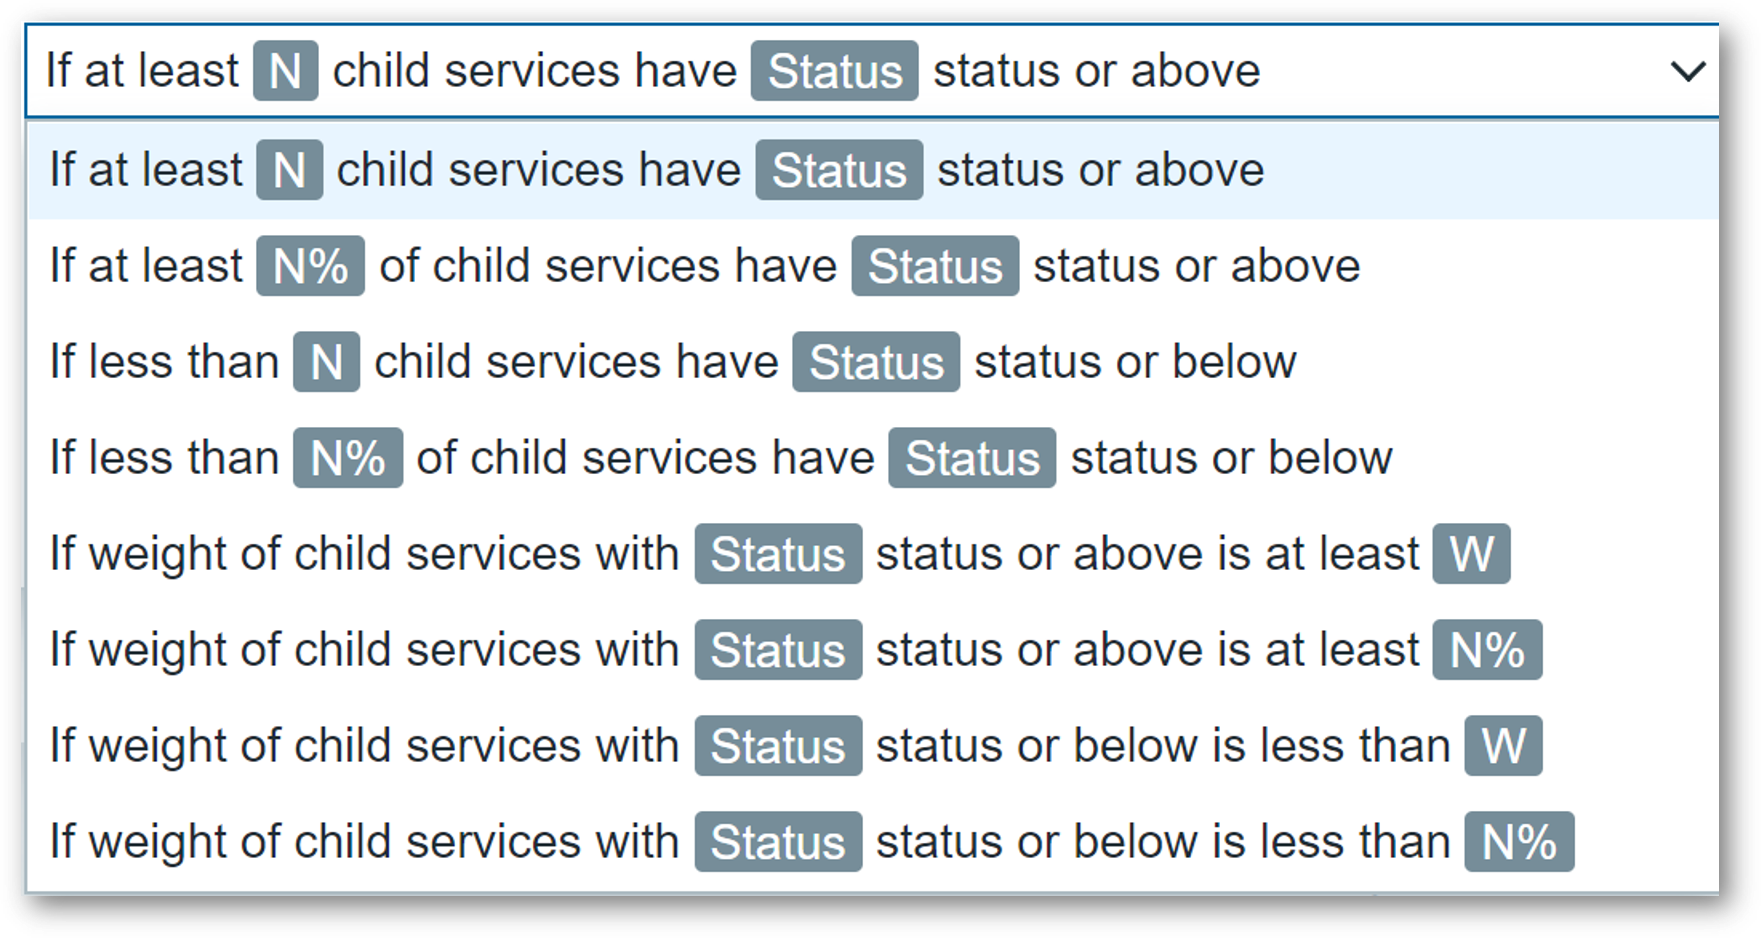
Changing the service status to a specific problem severity if:

  • At least N or N% of child services have a specific status
  • Define service weights and calculate the service status based on the service weights

There are many other additional features, all of which are covered in our Zabbix Summit Online 2021 speech dedicated to Business Service monitoring:

  • Ability to define permissions on specific services
  • SLA monitoring
  • Business Service root cause analysis
  • Receive alerts and react on Business Service status change
  • Define Business Service permissions for multi-tenant environments

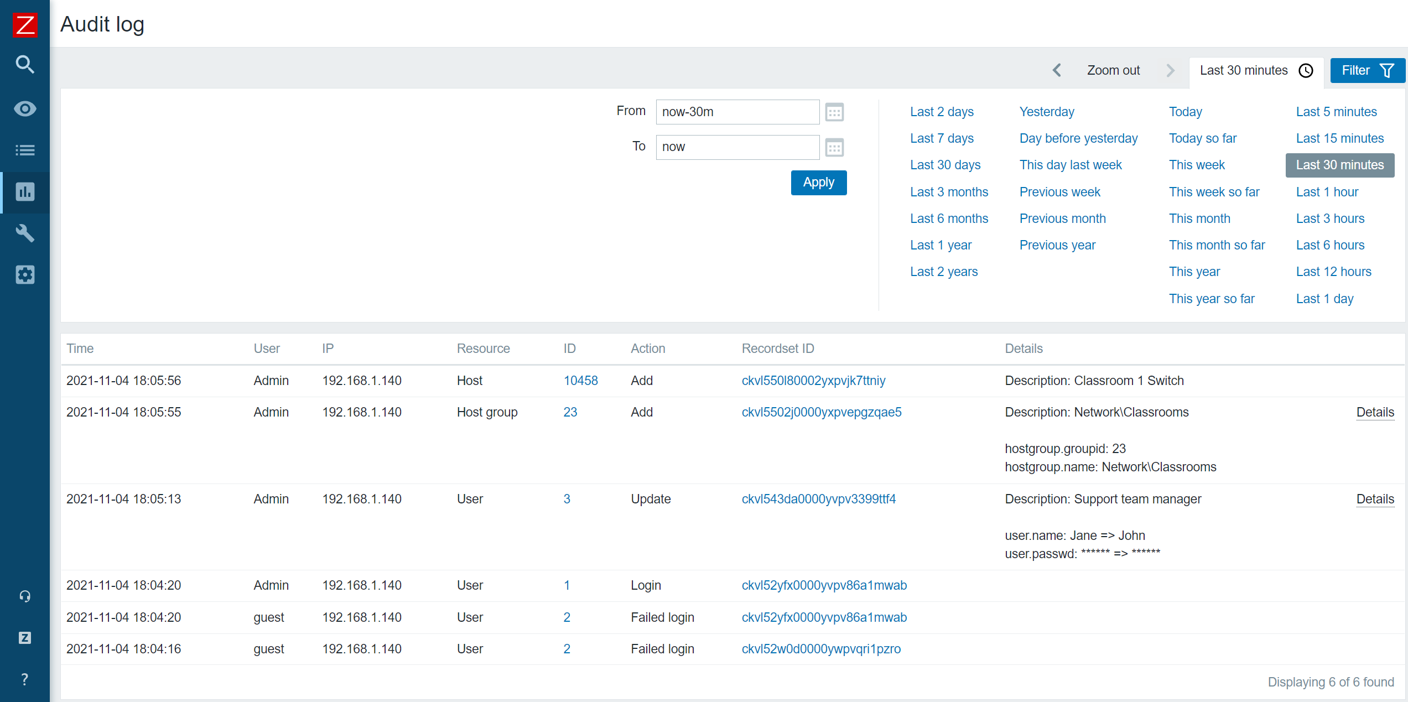
New Audit log schema

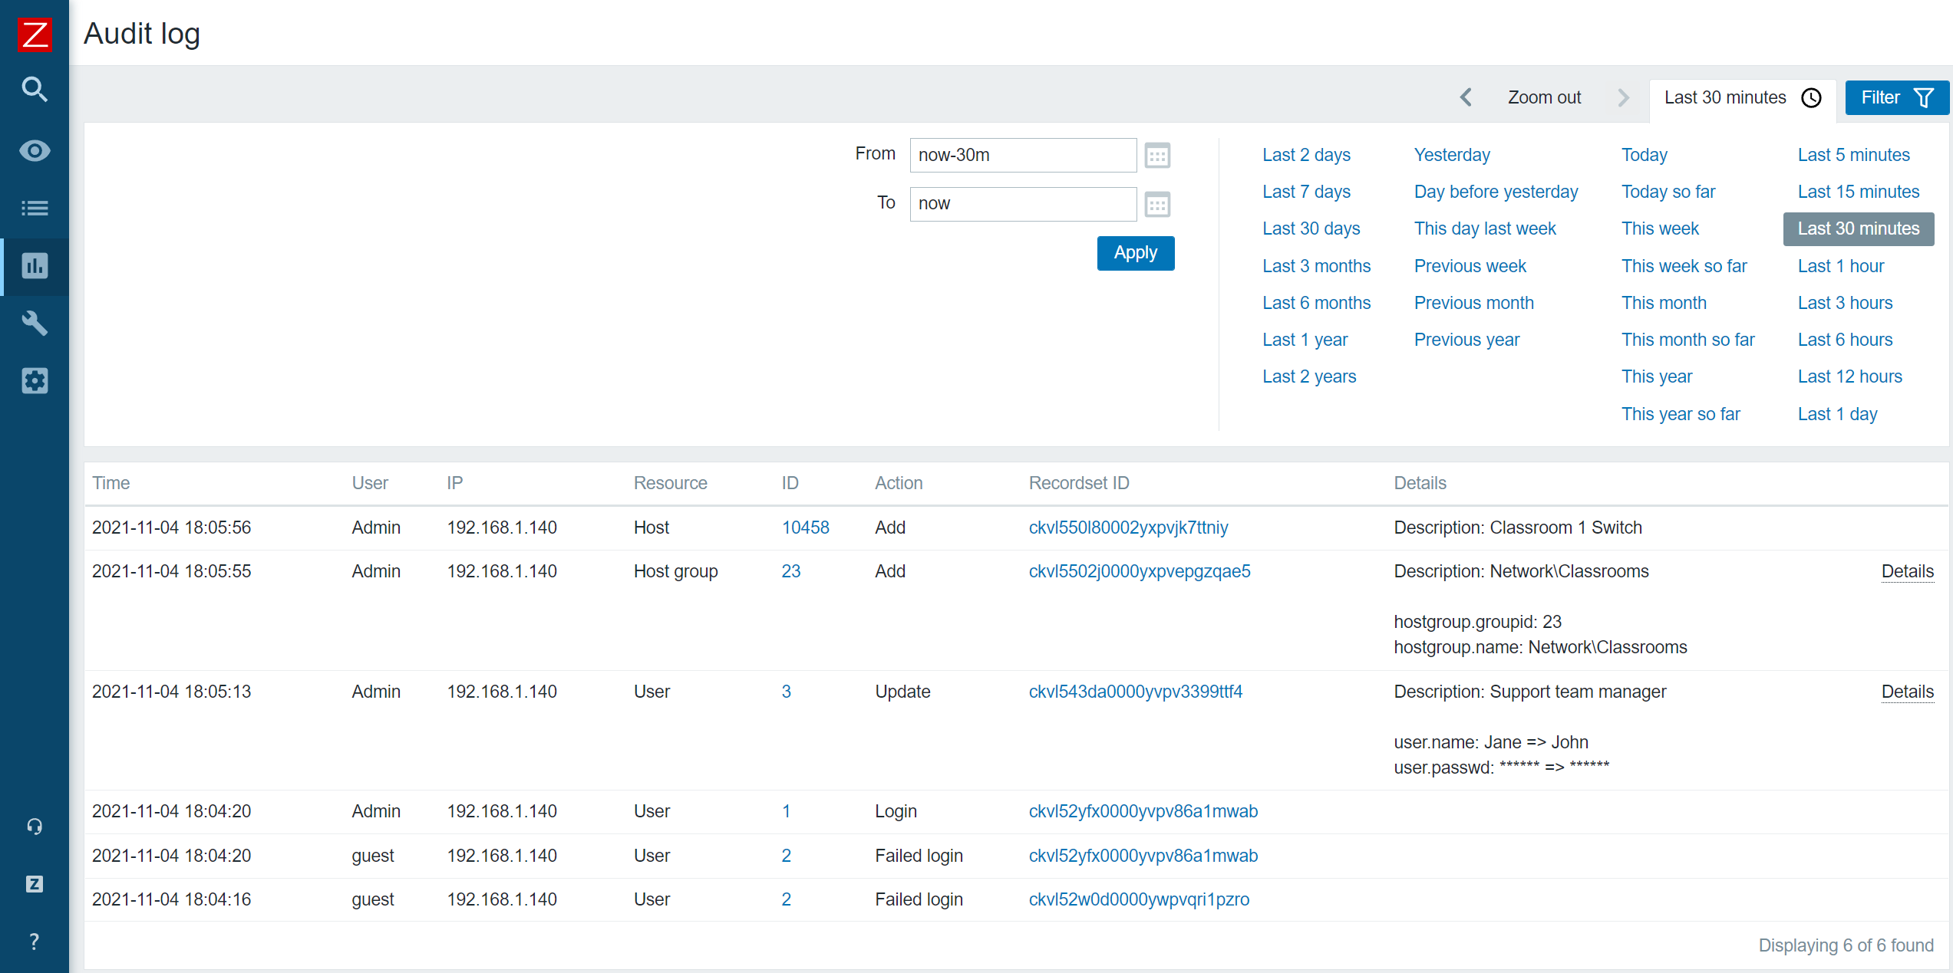
The existing audit log has been redesigned from scratch and now supports detailed logging for both Zabbix server and Zabbix frontend operations:

  • Zabbix 6.0 LTS introduces a new database structure for the Audit log
  • Collision resistant IDs (CUID) will be used for ID generation to prevent audit log row locks
  • Audit log records will be added in bulk SQL requests
  • Introducing Recordset ID column. This will help users recognize which changes have been made in a particular operation

The goal of the Zabbix 6.0 LTS audit log redesign is to provide reliable and detailed audit logging while minimizing the potential performance impact on large Zabbix instances:

  • Detailed logging of both Zabbix frontend and Zabbix server records
  • Designed with minimal performance impact in mind
  • Accessible via Zabbix API

Implementing the new audit log schema is an ongoing effort – further improvements will be done throughout the Zabbix update life cycle.

Machine learning

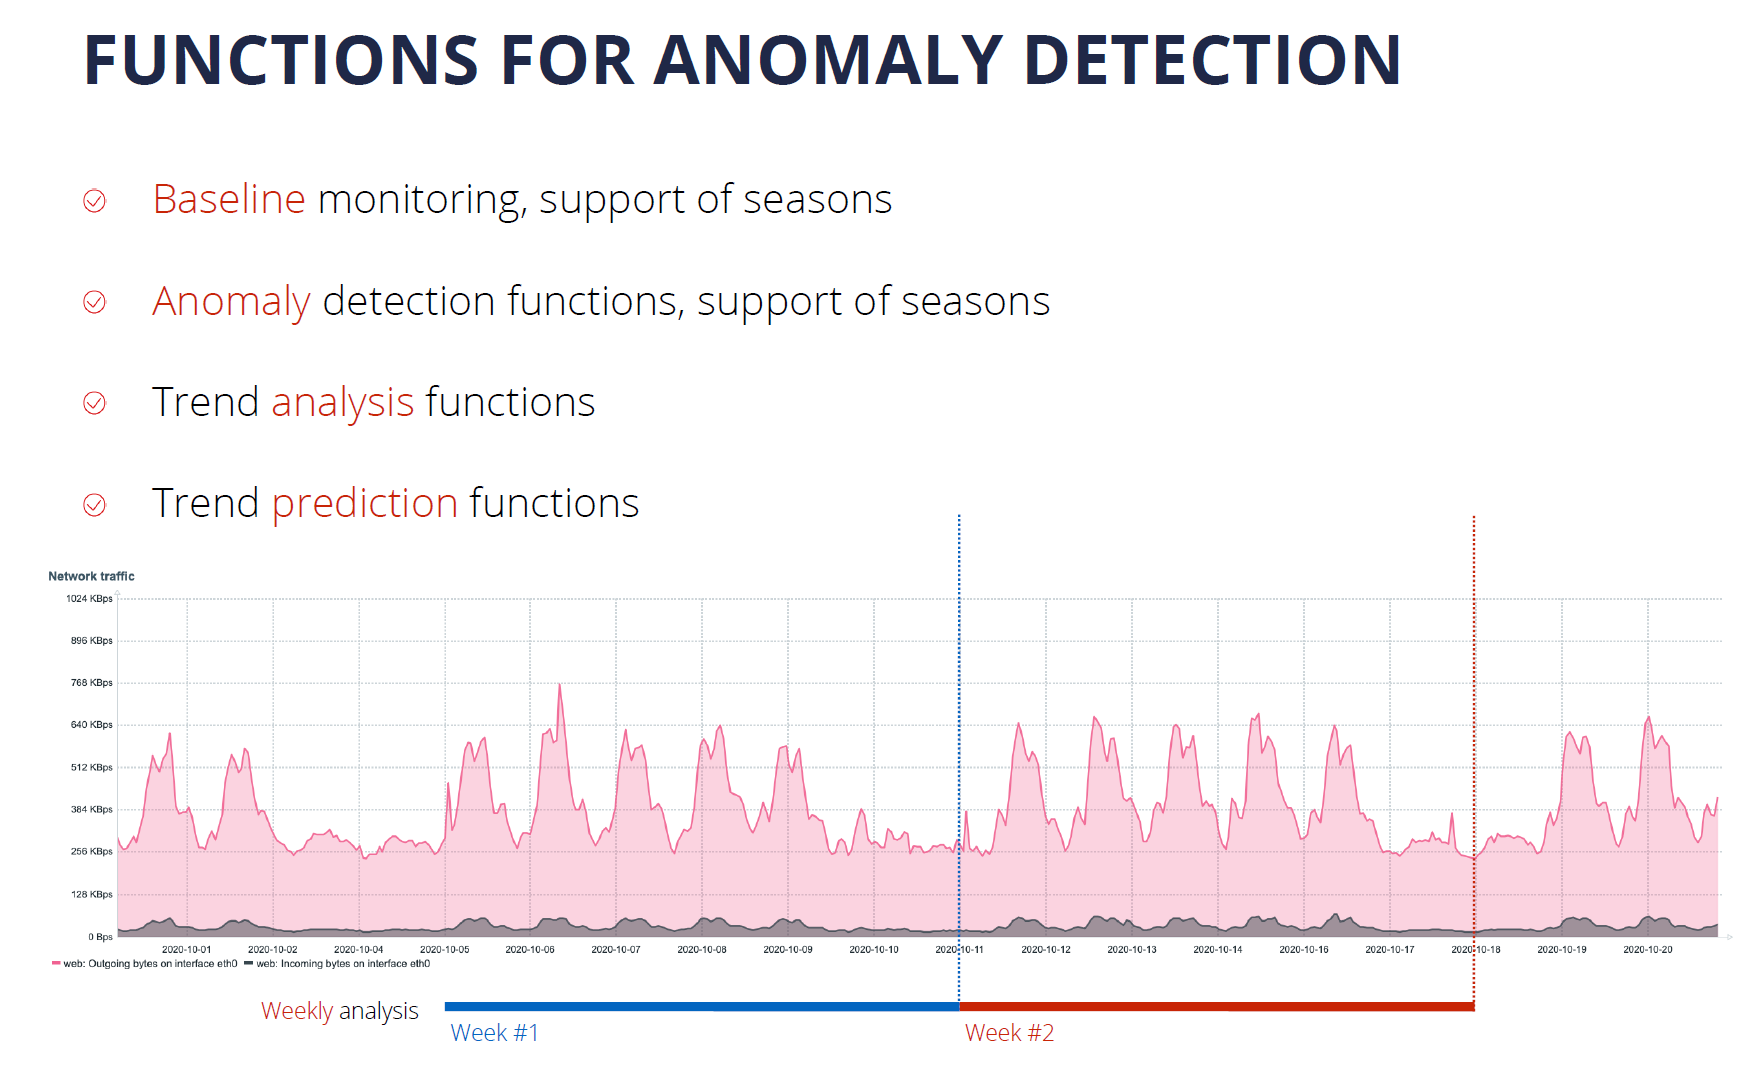
New trend functions have been added which utilize machine learning to perform anomaly detection and baseline monitoring:

  • New trend function – trendstl, allows you to detect anomalous metric behavior
  • New trend function – baselinewma, returns baseline by averaging data periods in seasons
  • New trend function – baselinedev, returns the number of standard deviations

An in-depth look into Machine learning in Zabbix 6.0 LTS is covered in our Zabbix Summit Online 2021 speech dedicated to machine learning, anomaly detection, and baseline monitoring.

New ways to visualize your data

Collecting and processing metrics is just a part of the monitoring equation. Visualization and the ability to display our infrastructure status in a single pane of glass are also vital to large environments. Zabbix 6.0 LTS adds multiple new visualization options while also improving the existing features.

  • The data table widget allows you to create a summary view for the related metric status on your hosts
  • The Top N and Bottom N functions of the data table widget allow you to have an overview of your highest or lowest item values
  • The single item widget allows you to display values for a single metric
  • Improvements to the existing vector graphs such as the ability to reference individual items and more
  • The SLA report widget displays the current SLA for services filtered by service tags

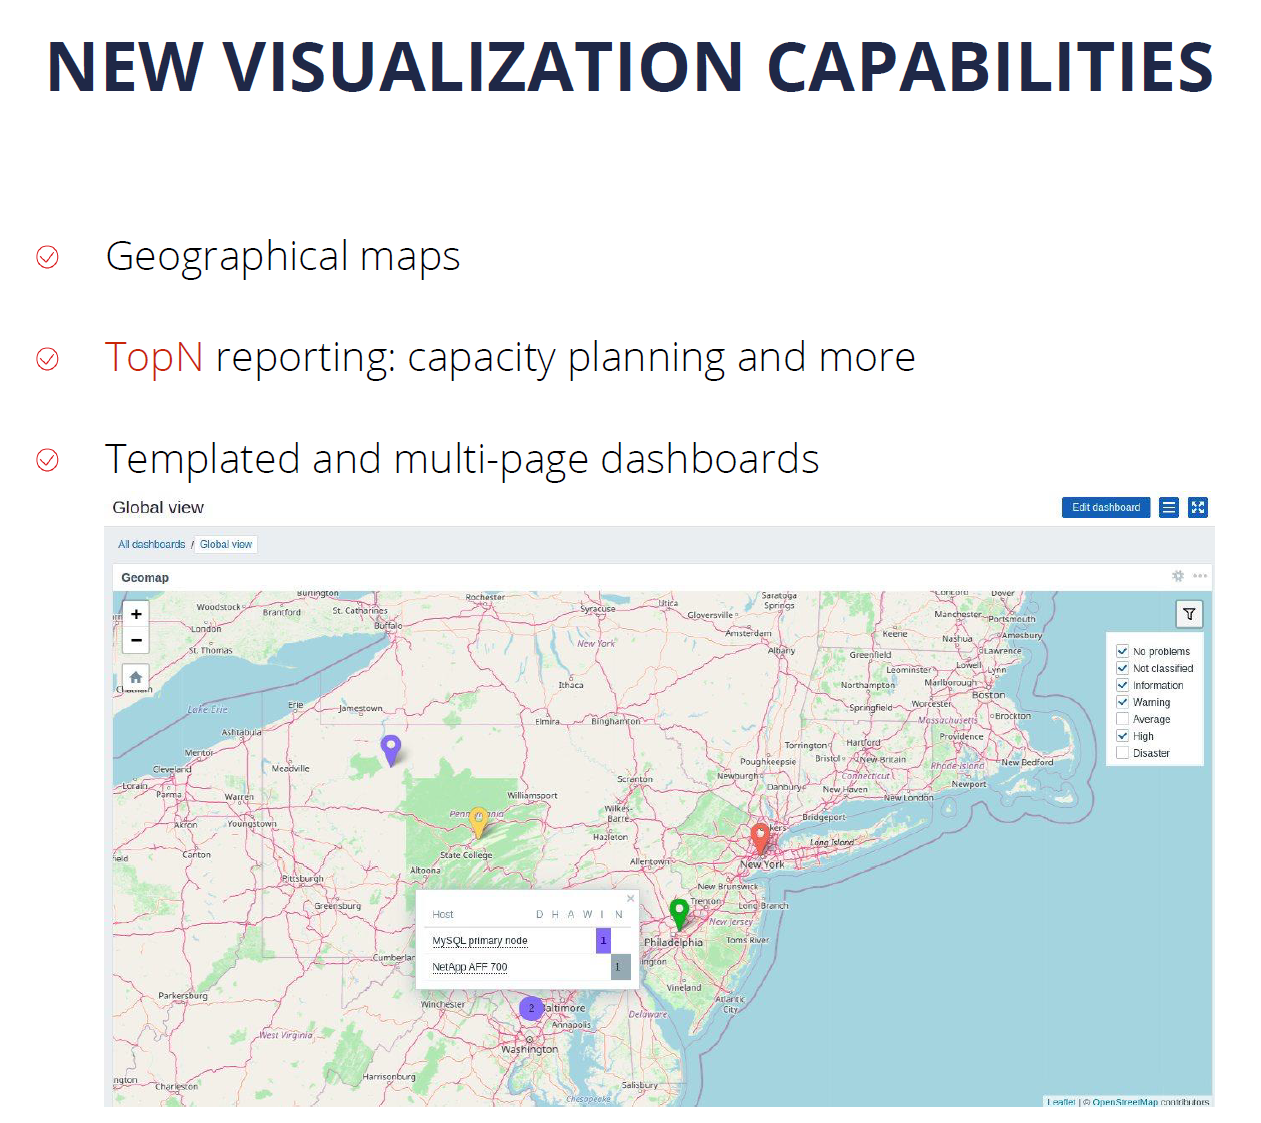
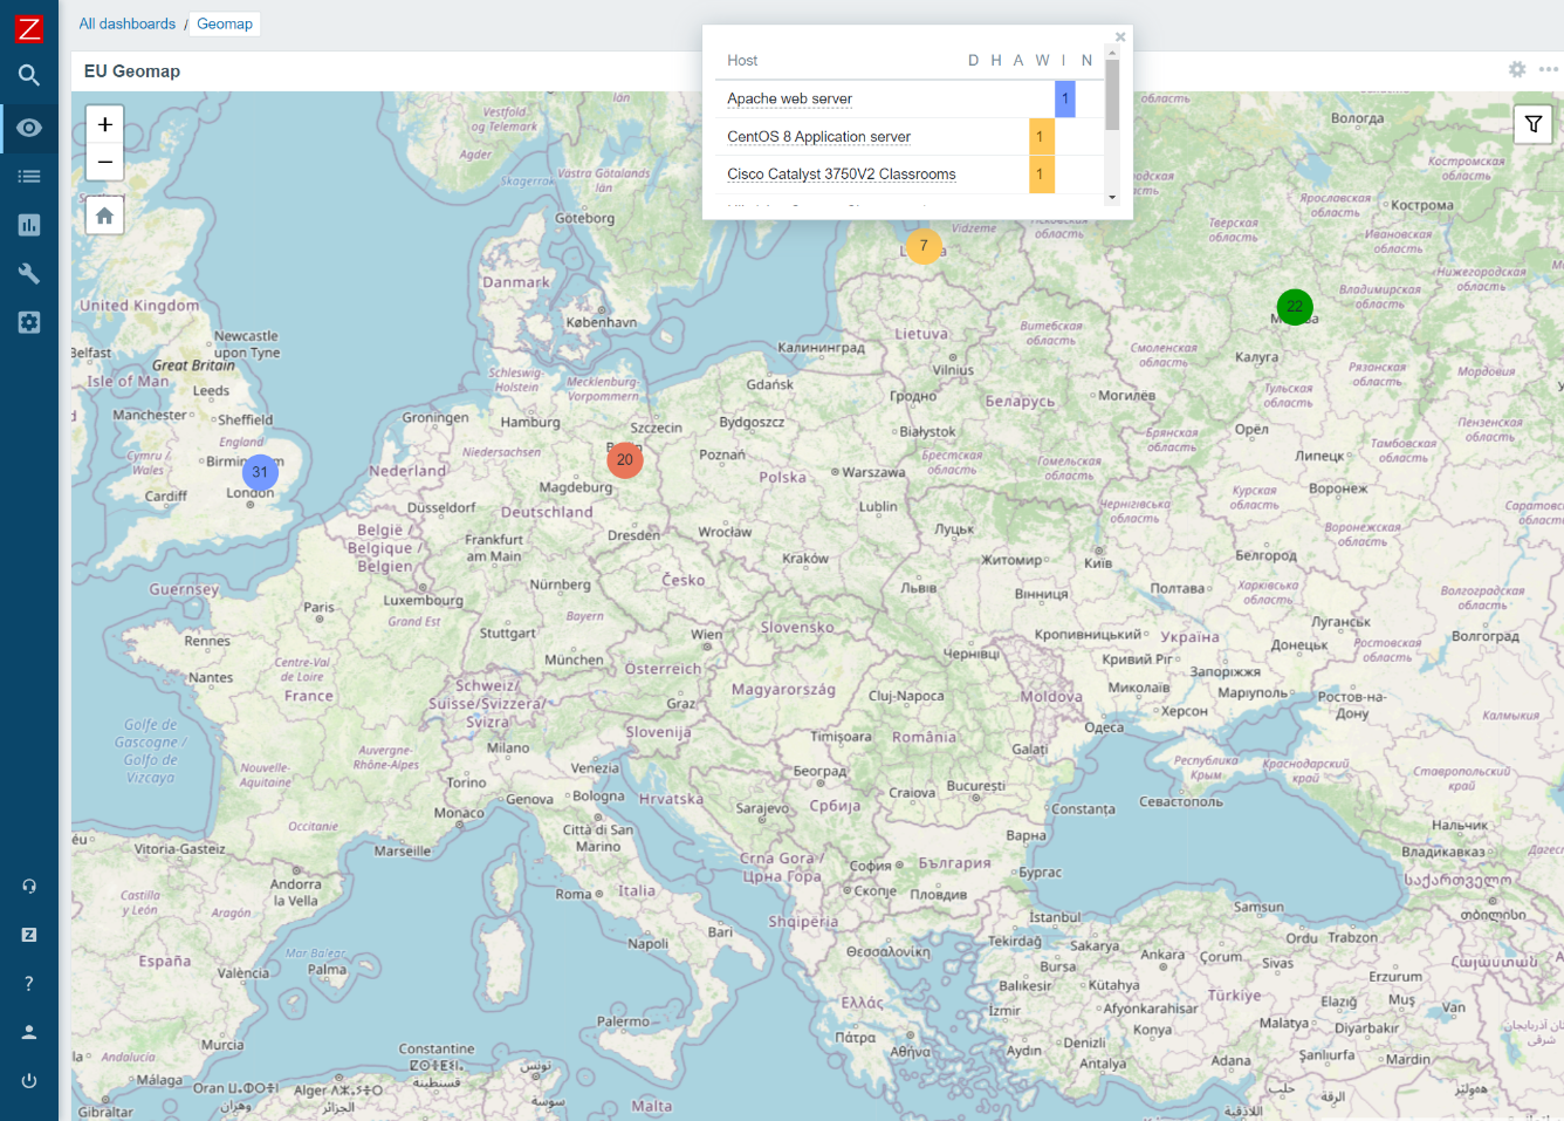
We are proud to announce that Zabbix 6.0 LTS will provide a native Geomap widget. Now you can take a look at the current status of your IT infrastructure on a geographic map:

  • The host coordinates are provided in the host inventory fields
  • Users will be able to filter the map by host groups and tags
  • Depending on the map zoom level – the hosts will be grouped into a single object
  • Support of multiple Geomap providers, such as OpenStreetMap, OpenTopoMap, Stamen Terrain, USGS US Topo, and others

Zabbix agent – improvements and new items

Zabbix agent and Zabbix agent 2 have also received some improvements. From new items to improved usability – both Zabbix agents are now more flexible than ever. The improvements include such features as:

  • New items to obtain additional file information such as file owner and file permissions
  • New item which can collect agent host metadata as a metric
  • New item with which you can count matching TCP/UDP sockets
  • It is now possible to natively monitor your SSL/TLS certificates with a new Zabbix agent2 item. The item can be used to validate a TLS/SSL certificate and provide you additional certificate details
  • User parameters can now be reloaded without having to restart the Zabbix agent

In addition, a major improvement to introducing new Zabbix agent 2 plugins has been made. Zabbix agent 2 now supports loading stand-alone plugins without having to recompile the Zabbix agent 2.

Custom Zabbix password complexity requirements

One of the main improvements to Zabbix security is the ability to define flexible password complexity requirements. Zabbix Super admins can now define the following password complexity requirements:

  • Set the minimum password length
  • Define password character requirements
  • Mitigate the risk of a dictionary attack by prohibiting the usage of the most common password strings

UI/UX improvements

Improving and simplifying the existing workflows is always a priority for every major Zabbix release. In Zabbix 6.0 LTS we’ve added many seemingly simple improvements, that have major impacts related to the “feel” of the product and can make your day-to-day workflows even smoother:

  • It is now possible to create hosts directly from MonitoringHosts
  • Removed MonitoringOverview section. For improved user experience, the trigger and data overview functionality can now be accessed only via dashboard widgets.
  • The default type of information for items will now be selected automatically depending on the item key.
  • The simple macros in map labels and graph names have been replaced with expression macros to ensure consistency with the new trigger expression syntax

New templates and integrations

Adding new official templates and integrations is an ongoing process and Zabbix 6.0 LTS is no exception here’s a preview for some of the new templates and integrations that you can expect in Zabbix 6.0 LTS:

  • f5 BIG-IP
  • Cisco ASAv
  • HPE ProLiant servers
  • Cloudflare
  • InfluxDB
  • Travis CI
  • Dell PowerEdge

Zabbix 6.0 also brings a new GitHub webhook integration which allows you to generate GitHub issues based on Zabbix events!

Other changes and improvements

But that’s not all! There are more features and improvements that await you in Zabbix 6.0 LTS. From overall performance improvements on specific Zabbix components, to brand new history functions and command-line tool parameters:

  • Detect continuous increase or decrease of values with new monotonic history functions
  • Added utf8mb4 as a supported MySQL character set and collation
  • Added the support of additional HTTP methods for webhooks
  • Timeout settings for Zabbix command-line tools
  • Performance improvements for Zabbix Server, Frontend, and Proxy

Questions and answers

Q: How can you configure geographical maps? Are they similar to regular maps?

A: Geomaps can be used as a Dashboard widget. First, you have to select a Geomap provider in the Administration – General – Geographical maps section. You can either use the pre-defined Geomap providers or define a custom one. Then, you need to make sure that the Location latitude and Location longitude fields are configured in the Inventory section of the hosts which you wish to display on your map. Once that is done, simply deploy a new Geomap widget, filter the required hosts and you’re all set. Geomaps are currently available in the latest alpha release, so you can get some hands-on experience right now.

Q: Any specific performance improvements that we can discuss at this point for Zabbix 6.0 LTS?

A: There have been quite a few. From the frontend side – we have improved the underlying queries that are related to linking new templates, therefore the template linkage performance has increased. This will be very noticeable in large instances, especially when linking or unlinking many templates in a single go.
There have also been improvements to Server – Proxy communication. Specifically – the logic of how proxy frees up uncompressed data. We’ve also introduced improvements on the DB backend side of things – from general improvements to existing queries/logic, to the introduction of primary keys for history tables, which we are still extensively testing at this point.

Q: Will you still be able to change the type of information manually, in case you have some advanced preprocessing rules?

A: In Zabbix 6.0 LTS Zabbix will try and automatically pick the corresponding type of information for your item. This is a great UX improvement since you don’t have to refer to the documentation every time you are defining a new item. And, yes, you will still be able to change the type of information manually – either because of preprocessing rules or if you’re simply doing some troubleshooting.

Zabbix 6.0 LTS – The next great leap in monitoring by Alexei Vladishev / Zabbix Summit Online 2021

Post Syndicated from Alexei Vladishev original https://blog.zabbix.com/zabbix-6-0-lts-the-next-great-leap-in-monitoring-by-alexei-vladishev-zabbix-summit-online-2021/17683/

The Zabbix Summit Online 2021 keynote speech by Zabbix founder and CEO Alexei Vladishev focuses on the role of Zabbix in modern, dynamic IT infrastructures. The keynote speech also highlights the major milestones leading up to Zabbix 6.0 LTS and together we take a look at the future of Zabbix.

The full recording of the speech is available on the official Zabbix Youtube channel.

Digital transformation journey
Infrastructure monitoring challenges
Zabbix – Universal Open Source enterprise-level monitoring solution
Cost-Effectiveness
Deploy Anywhere
Monitor Anything
Monitoring of Kubernetes and Hybrid Clouds
Data collection and Aggregation
Security on all levels
Powerful Solution for MSPs
Scalability and High Availability
Machine learning and Statistical analysis
More value to users
New visualization capabilities
IoT monitoring
Infrastructure as a code
Tags for classification
What’s next?
Advanced event correlation engine
Multi DC Monitoring
Zabbix Release Schedule
Zabbix Roadmap
Questions

Digital transformation journey

First, let’s talk about how Zabbix plays a role as a part of the Digital Transformation journey for many companies.

As IT infrastructures evolve, there are many ongoing challenges. Most larger companies for example have a set of legacy systems that require to be integrated with more modern systems. This results in a mix of legacy and new technologies and protocols. This means that most management and monitoring tools need to support all of these technologies – Zabbix is no exception here.

Hybrid clouds, containers, and container orchestration systems such as K8S and OpenShift have also played an immense part in the digital transformation of enterprises. It has been a very major paradigm shift – from physical machines to virtual machines, to containers and hybrid parts. We certainly must provide the required set of technologies to monitor such environments and the monitoring endpoints unique to them.

The rapid increase in the complexity of IT infrastructures caused by the two previous points requires our tools to be a lot more scalable than before. We have many more moving parts, likely located in different locations that we need to stay aware of. This also means that any downtime is not acceptable – this is why the high availability of our tools is also vital to us.

Let’s not forget that with increased complexity, many new potential security attack vectors arise and our tools need to support features that can help us with minimizing the security risks.

But making our infrastructures more agile usually comes at a very real financial cost. We must not forget that most of the time we are working with a dedicated budget for our tools and procedures.

Infrastructure monitoring challenges

The increase in the complexity of IT infrastructures also poses multiple monitoring challenges that we have to strive to overcome:

  • Requirements for scalability and high availability for our tools
    • The growing number of devices and networks as well as the increased complexity of IT infrastructures
  • Increasingly complex infrastructures often force us to utilize multiple tools to obtain the required metrics
    • This leads to a requirement for a single pane of glass to enable centralized monitoring
  • Collecting values is often not enough – we need to be able to leverage the collected data to gain the most value out of it
  • We need a solution that can deliver centralized visualization and reporting based on the obtained data
  • Our tools need to be hand-picked so that they can deliver the best ROI in an already complex infrastructure

Zabbix – Universal Open Source enterprise-level monitoring solution

Zabbix is a Universal free and Open Source enterprise-level monitoring solution. The tool comes at absolutely no cost and is available for everyone to try out and use. Zabbix provides the monitoring of modern IT infrastructures on multiple levels.

Universal is the term that we are focusing on. Given the open-source nature of the product, Zabbix can be used in infrastructures of different sizes – from small and medium organizations to large, globe-spanning enterprises. Zabbix is also capable of delivering monitoring of the whole IT stack – from hardware and network monitoring to high-level monitoring such as Business Service monitoring and more.

Cost-Effectiveness

Zabbix delivers a large set of enterprise-grade features at no cost! Features such as 2FA, Single sign-on solutions, no restrictions when it comes to data collection methods, number of monitored devices and services, or database size.

  • Exceptionally low total cost of ownership
    • Free and Open Source solution with quality and security in mind
    • Backed by reliable vendors, a global partner network, and commercial services, such as the 24/7 support
    • No limitations regarding how you use the software
    • Free and readily available documentation, HOWTOs, community resources, videos, and more.
    • Zabbix engineers are easy to find and hire for your organization
    • Cost is fully under your control – Zabbix Commercial services are under fixed-price agreements

Deploy Anywhere

Our users always have the choice of where and how they wish to deploy Zabbix. With official packages for the most popular operating systems such as RHEL, Oracle Linux, Ubuntu, Raspberry Pi OS, and more. With official Helm charts, you can quickly also deploy Zabbix in a Kubernetes cluster or in your OpenShift instance. We also provide official Docker container images with pre-installed Zabbix components that you can deploy in your environment.

We also provide one-click deployment options for multiple cloud service providers, such as Amazon AWS, Microsoft Azure, Google Cloud, Openstack, and many other cloud service providers.

Monitor Anything

With Zabbix, you can monitor anything – from legacy solutions to modern systems. With a large selection of official solutions and substantial community backing our users can be sure that they can find a suitable approach to monitor their IT infrastructure components. There are hundreds of ready-to-use monitoring solutions by Zabbix.

Whenever you deploy a new IT solution in your enterprise, you will want to tie it together with the existing toolset. Zabbix provides many out of the box integrations for the most popular ticketing and alerting systems

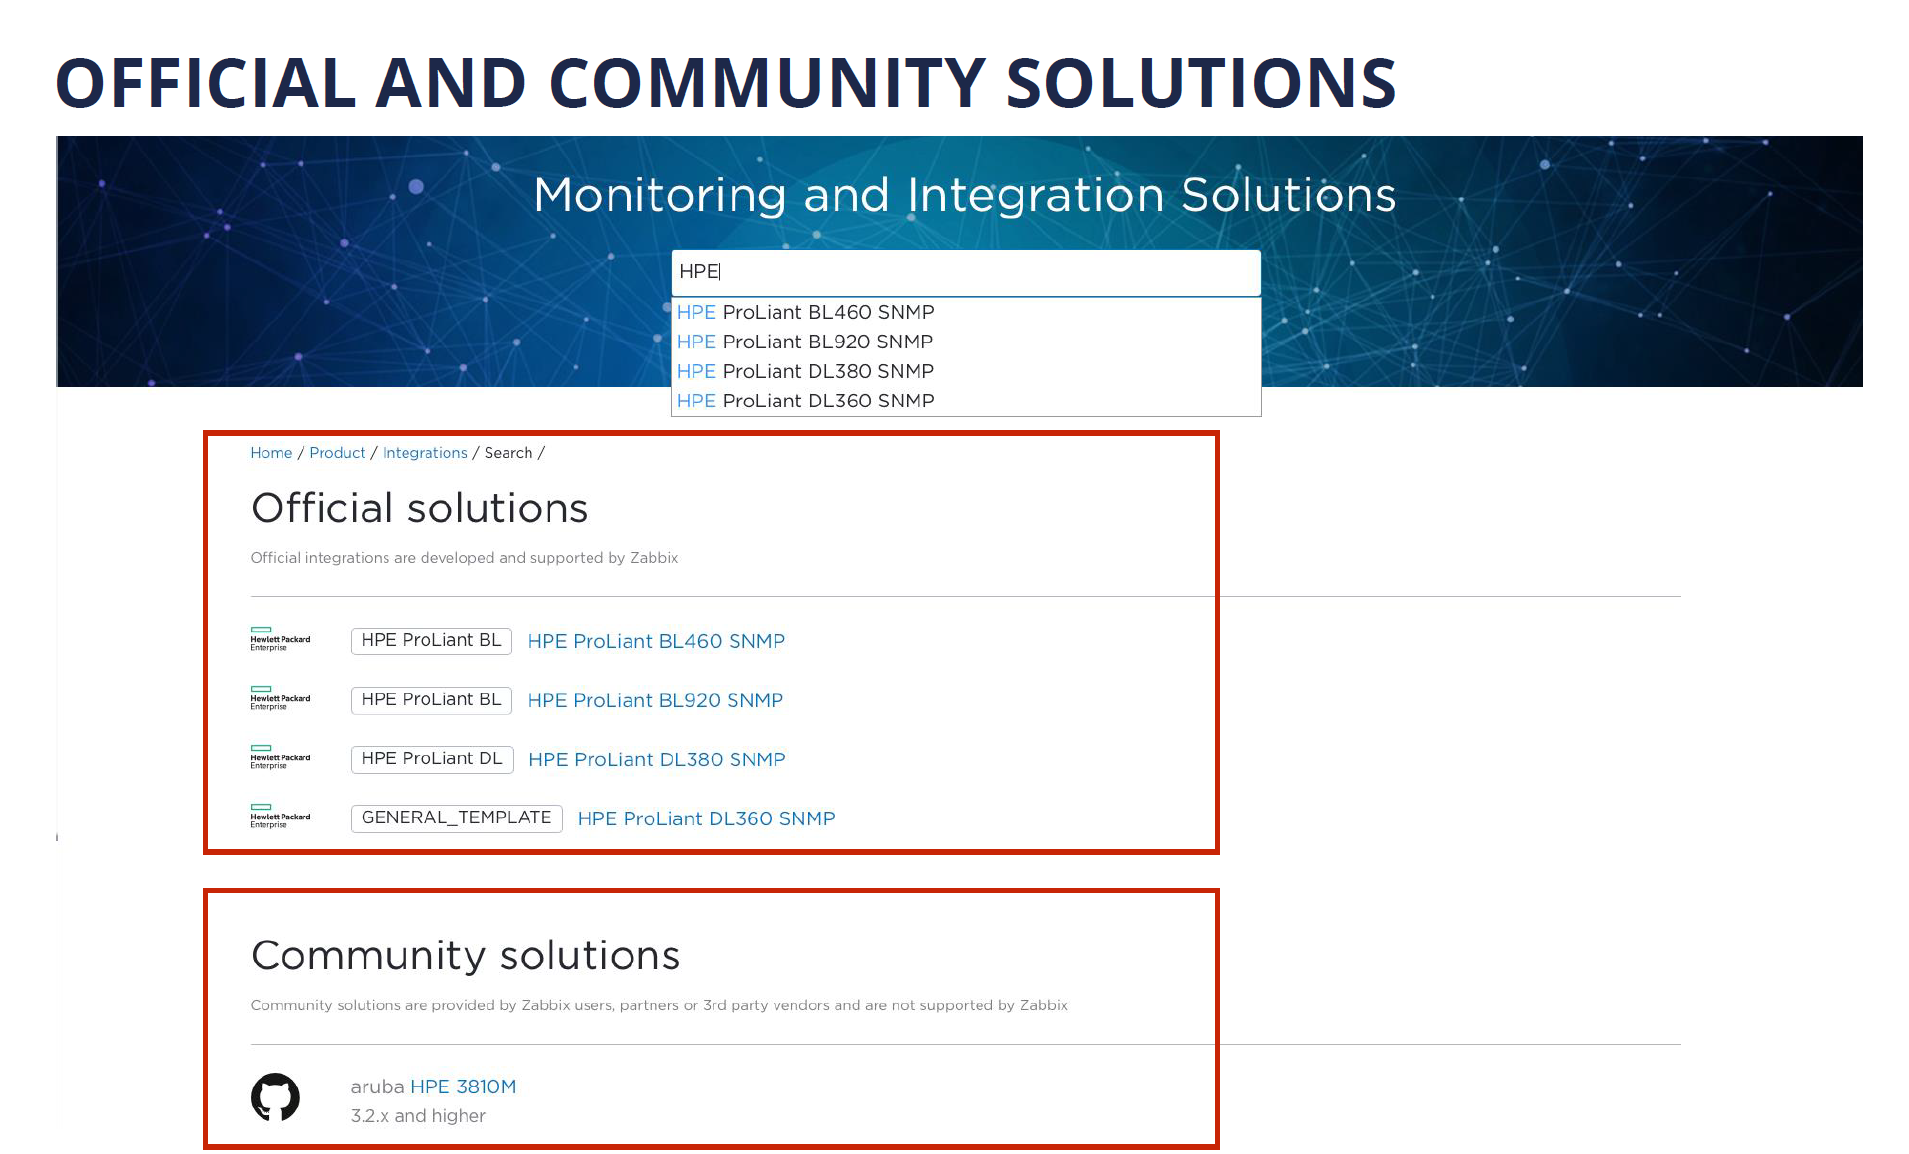
Recently we have introduced advanced search capabilities for the Zabbix integrations page, which allows you to quickly lookup the integrations that currently exist on the market. If you visit the Zabbix integrations page and look up a specific vendor or tool, you will see a list of both the official solutions supported by Zabbix and also a long list of community solutions backed by our users, partners, and customers.

Monitoring of Kubernetes and Hybrid Clouds

Nowadays many existing companies are considering migrating their existing infrastructure to either solutions such as Kubernetes or OpenShift, or utilizing cloud service providers such as Amazon AWS or Microsoft Azure.

I am proud to announce, that with the release of Zabbix 6.0 LTS, Zabbix will officially support out-of-the-box monitoring of OpenShfit and Kubernetes clusters.

Data collection and Aggregation

Let’s cover a few recent features that improve the out-of-the-box flexibility of Zabbix by a large margin.

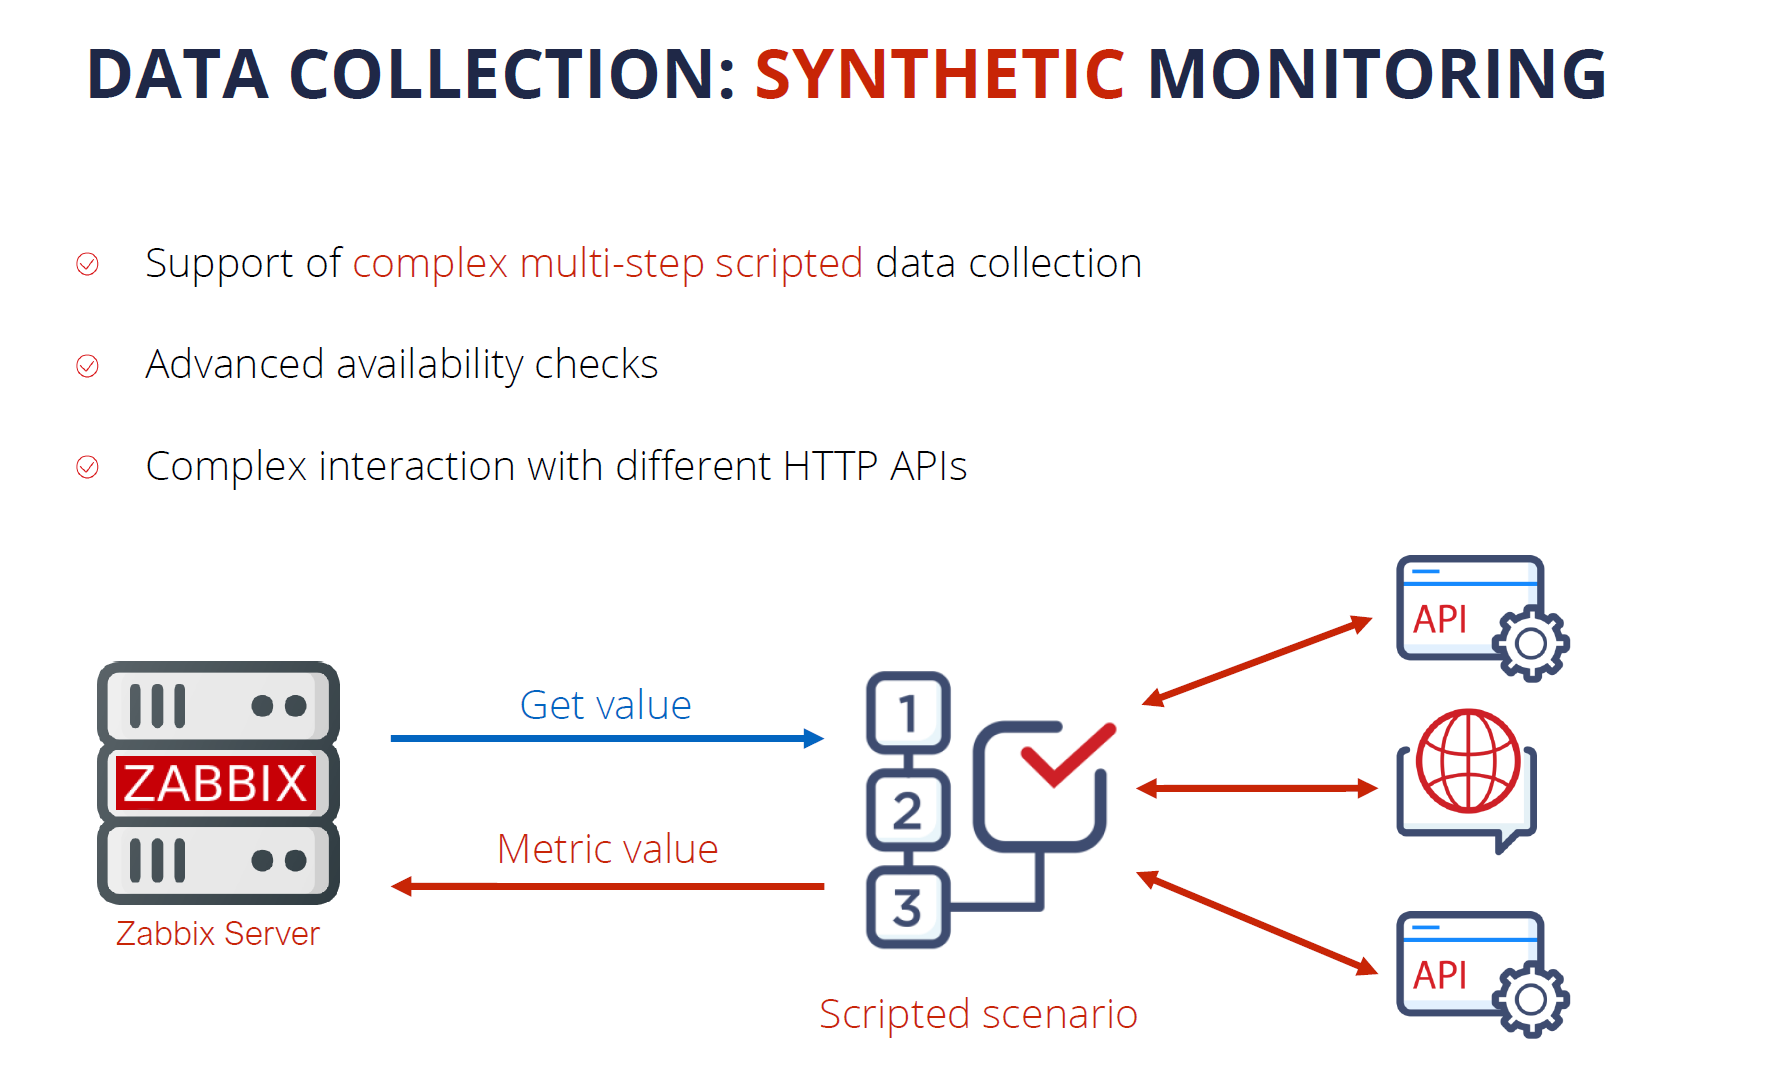
Synthetic monitoring is a feature that was introduced a year ago in Zabbix version 5.2 and it has already become quite popular with our user base. The feature enables monitoring of different devices and solutions over the HTTP protocol. By using synthetic monitoring Zabbix can connect to your HTTP endpoints, such as cloud APIs, Kubernetes, and OpenShift APIs, and other HTTP endpoints, collect the metrics and then process them to extract the required information. Synthetic monitoring is extremely transparent and flexible – it can be fine-tuned to communicate with any HTTP endpoints.

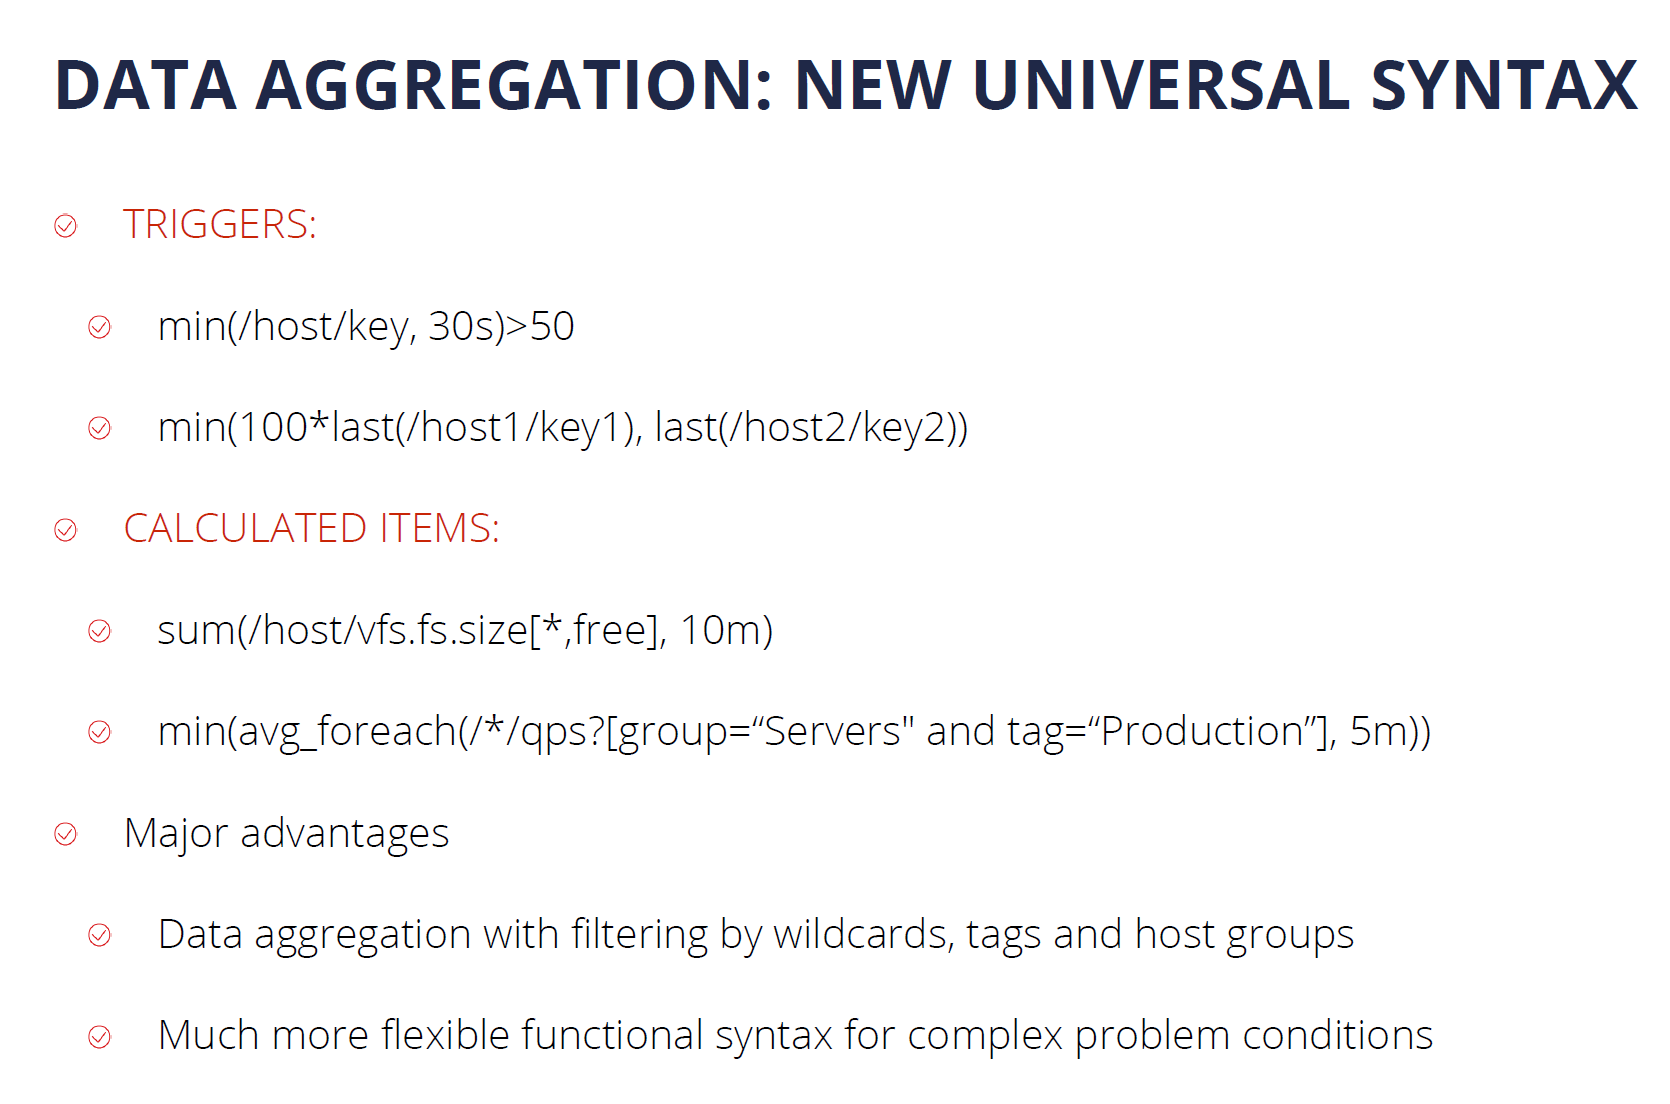
Another major feature introduced in Zabbix 5.4 is the new trigger syntax. This enables our users to define much more flexible trigger expressions, supporting many new problem detection use cases. In addition, we can use this syntax to perform flexible data aggregation operations. For example, now we can aggregate data filtered by wildcards, tags, and host groups, instead of specifying individual items. This is extremely valuable for monitoring complex infrastructures, such as Kubernetes or cloud environments. At the same time, the new syntax is a lot more simple to learn and understand when compared to the old trigger syntax.

Security on all levels

Many companies are concerned about security and data protection when it comes to the tools that they are using in their day-to-day tasks. I’m happy to tell you that Zabbix follows the highest security standards when it comes to the development and usage of the product.

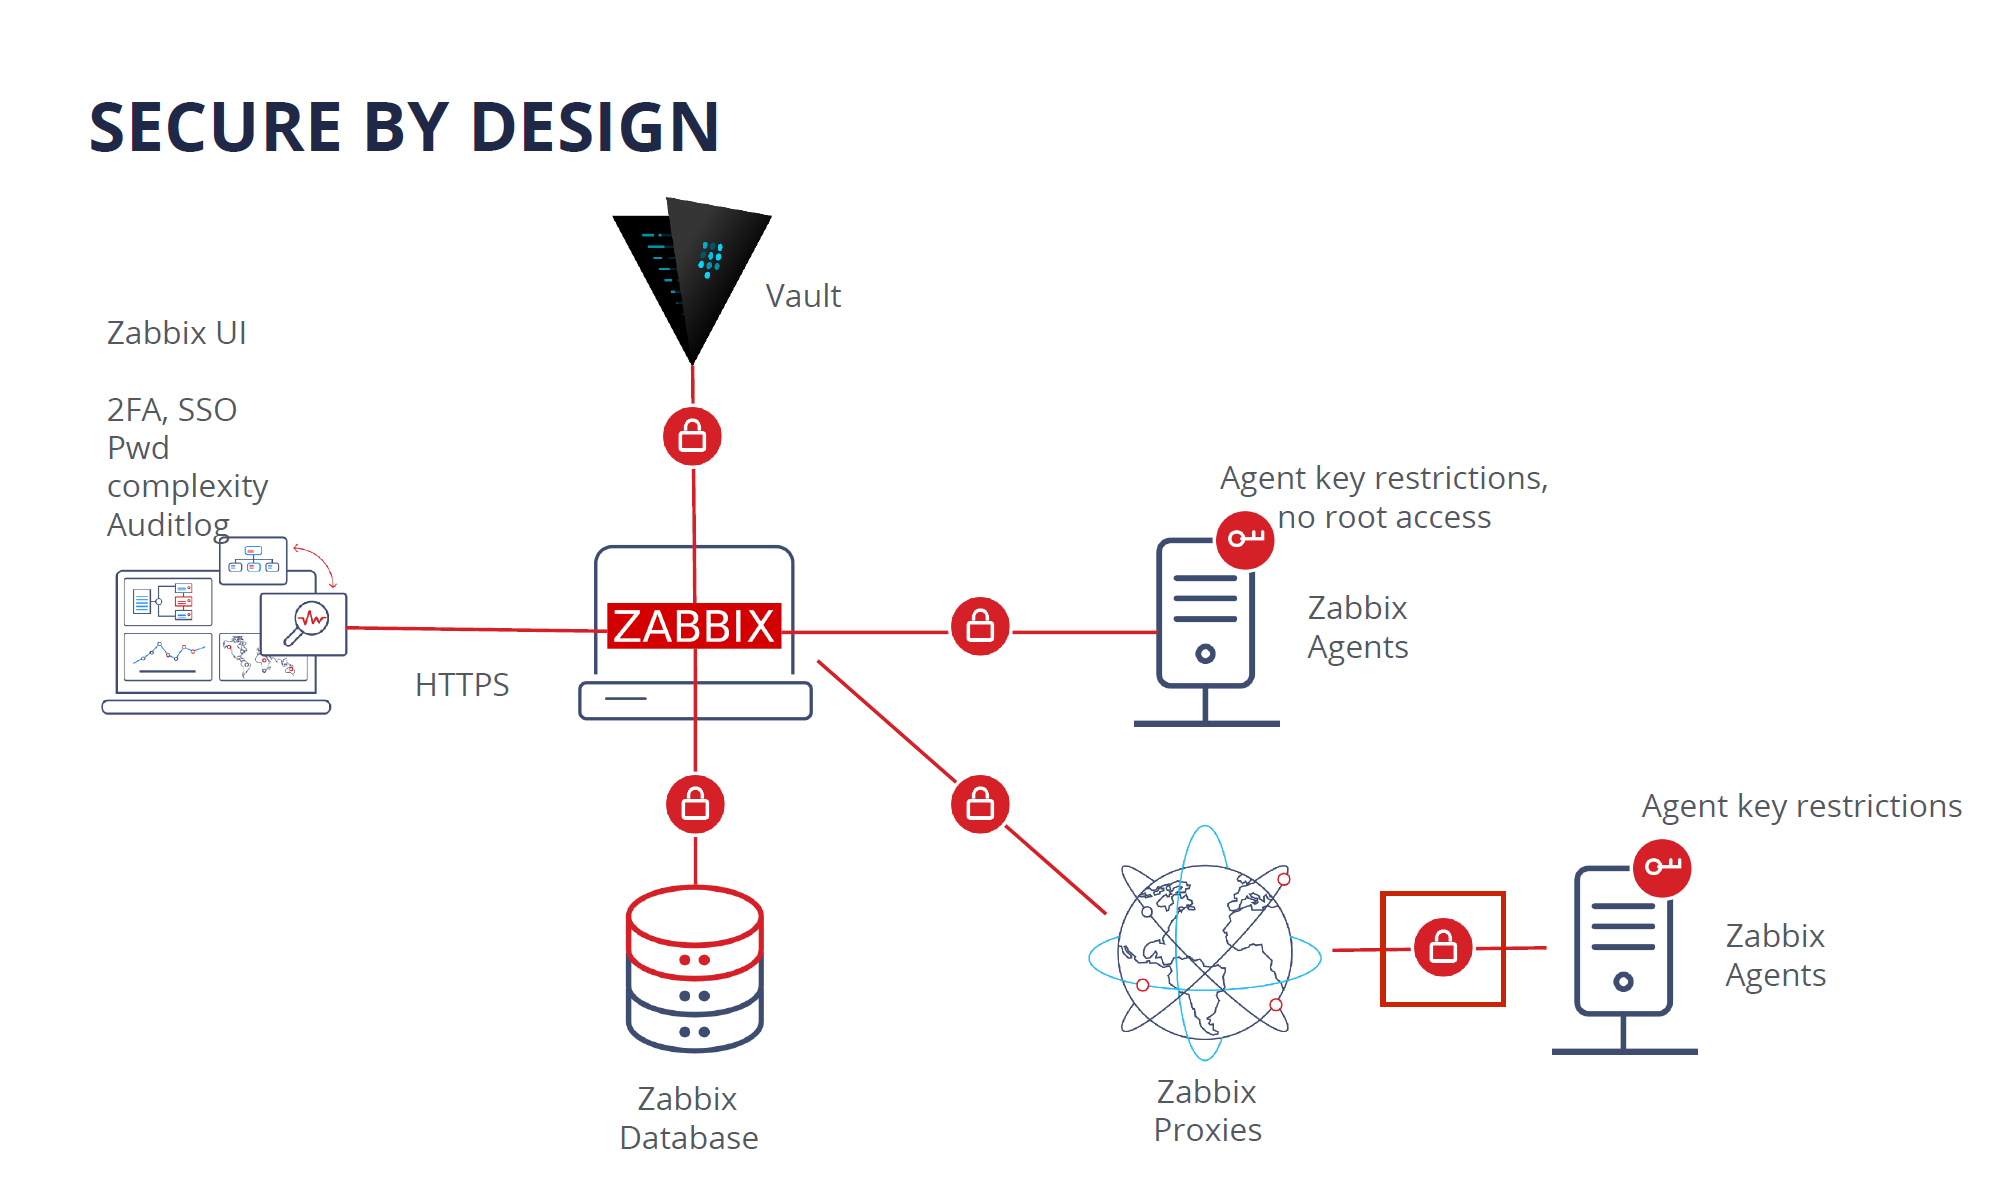
Zabbix is secure by design. In the diagram below you can see all of the Zabbix components, all of which are interconnected, like Zabbix Agent, Server, Proxy, Database, and Frontend. All of the communication between different Zabbix components can be encrypted by using strong encryption protocols like TLS.

If you’re using Zabbix Agent, the agent does not require root privileges. You can run Zabbix Agent under a normal user with all of the necessary user level restrictions in place. Zabbix agent can also be restricted with metric allow and deny lists, so it has access only to the metrics which are permitted for collection by your company policies.

The connections between the Zabbix database backend and the Zabbix Frontend and Zabbix Server also support encryption as of version 5.0 LTS.

As for the frontend component – users can add an additional security layer for their Zabbix frontends by configuring 2FA and SSO logins. Zabbix 6.0 LTS also introduces flexible login password complexity requirements, which can reduce the security breach risk if your frontend is exposed to the internet. To ensure that Zabbix meets the highest standards of the company security compliance, the new Audit log, introduced in Zabbix 6.0 LTS, is capable of logging all of the Zabbix Frontend and Zabbix Server operations.

For an additional security layer – sensitive information like Usernames, Passwords, API keys can be stored in an external vault. Currently, Zabbix supports secret storage in the HashiCorp Vault. Support for the CyberArk vault will be added in the Zabbix 6.2 release.

Another Zabbix feature – the Zabbix API, is often used for the automation of day-to-day configuration workflows, as well as custom integrations and data migration tasks. Zabbix 5.4 added the ability to create API tokens for particular frontend users with pre-defined token expiration dates.

In Zabbix 5.2 we added another layer for the Zabbix Frontend user permissions – User Roles. Now it is possible to define granular user roles with different types of rights and privileges, assigned to specific types of users in your organization. With User Roles, we can define which parts of the Zabbix UI the specific user role has access to and which UI actions the members of this role can perform. This can be combined with API method restrictions which can also be defined for a particular role.

Powerful Solution for MSPs

When we combine all of these features, we can see how Zabbix becomes a powerful solution for MSP customers. MSPs can use Zabbix as an added value service. This way they can provide a monitoring service for their customers and get additional revenue out of it. It is possible to build a customer portal which is a combination of User Roles for read-only access to dashboards and customized UI, rebranding option – which was just introduced in Zabbix 6.0 LTS, and a combination of SLA reporting together with scheduled PDF reports, so the customers can receive reports on a weekly, daily or monthly basis.

Scalability and High Availability

With a growing number of devices and ever-increasing network complexity, Scalability and High availability are extremely important requirements.

Zabbix provides Load balancing options for Zabbix UI and Zabbix API. In order to scale the Zabbix Frontend and Zabbix API, we can simply deploy additional Zabbix Frontend nodes, thus introducing redundancy and high availability.

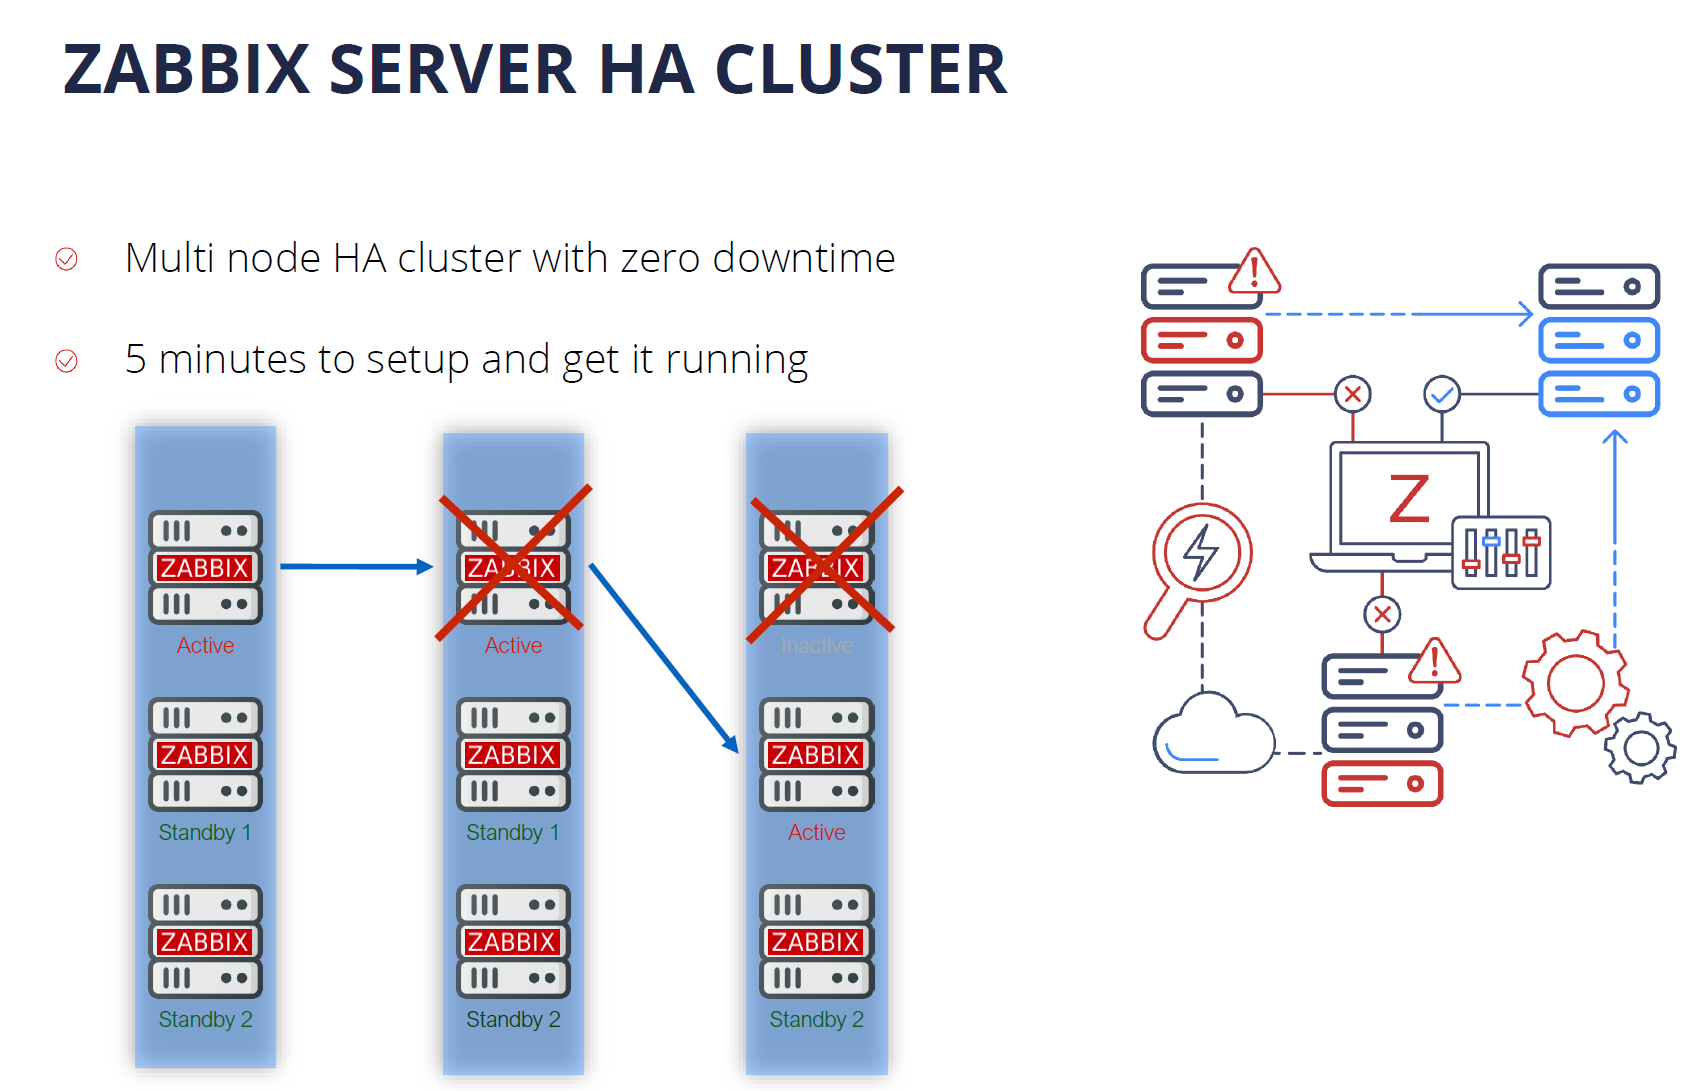
Zabbix 6.0 LTS comes with out-of-the-box support for the Zabbix Server High Availability cluster. If one of the Zabbix Server nodes goes down, Zabbix will automatically switch to one of the standby nodes. And the best thing about the Zabbix Server High Availability cluster – it takes only 5 minutes to get it up and running. the HA cluster is very easy to configure and use.

One of the features in our future roadmap is introducing support for the History API to work with different time-series DB backends for extra efficiency and scalability. Another feature that we would like to implement in the future is load balancing for Zabbix Servers and Zabbix Proxies. Combining all of these features would truly make Zabbix a cloud-native application with unlimited horizontal scalability.

Machine learning and Statistical analysis

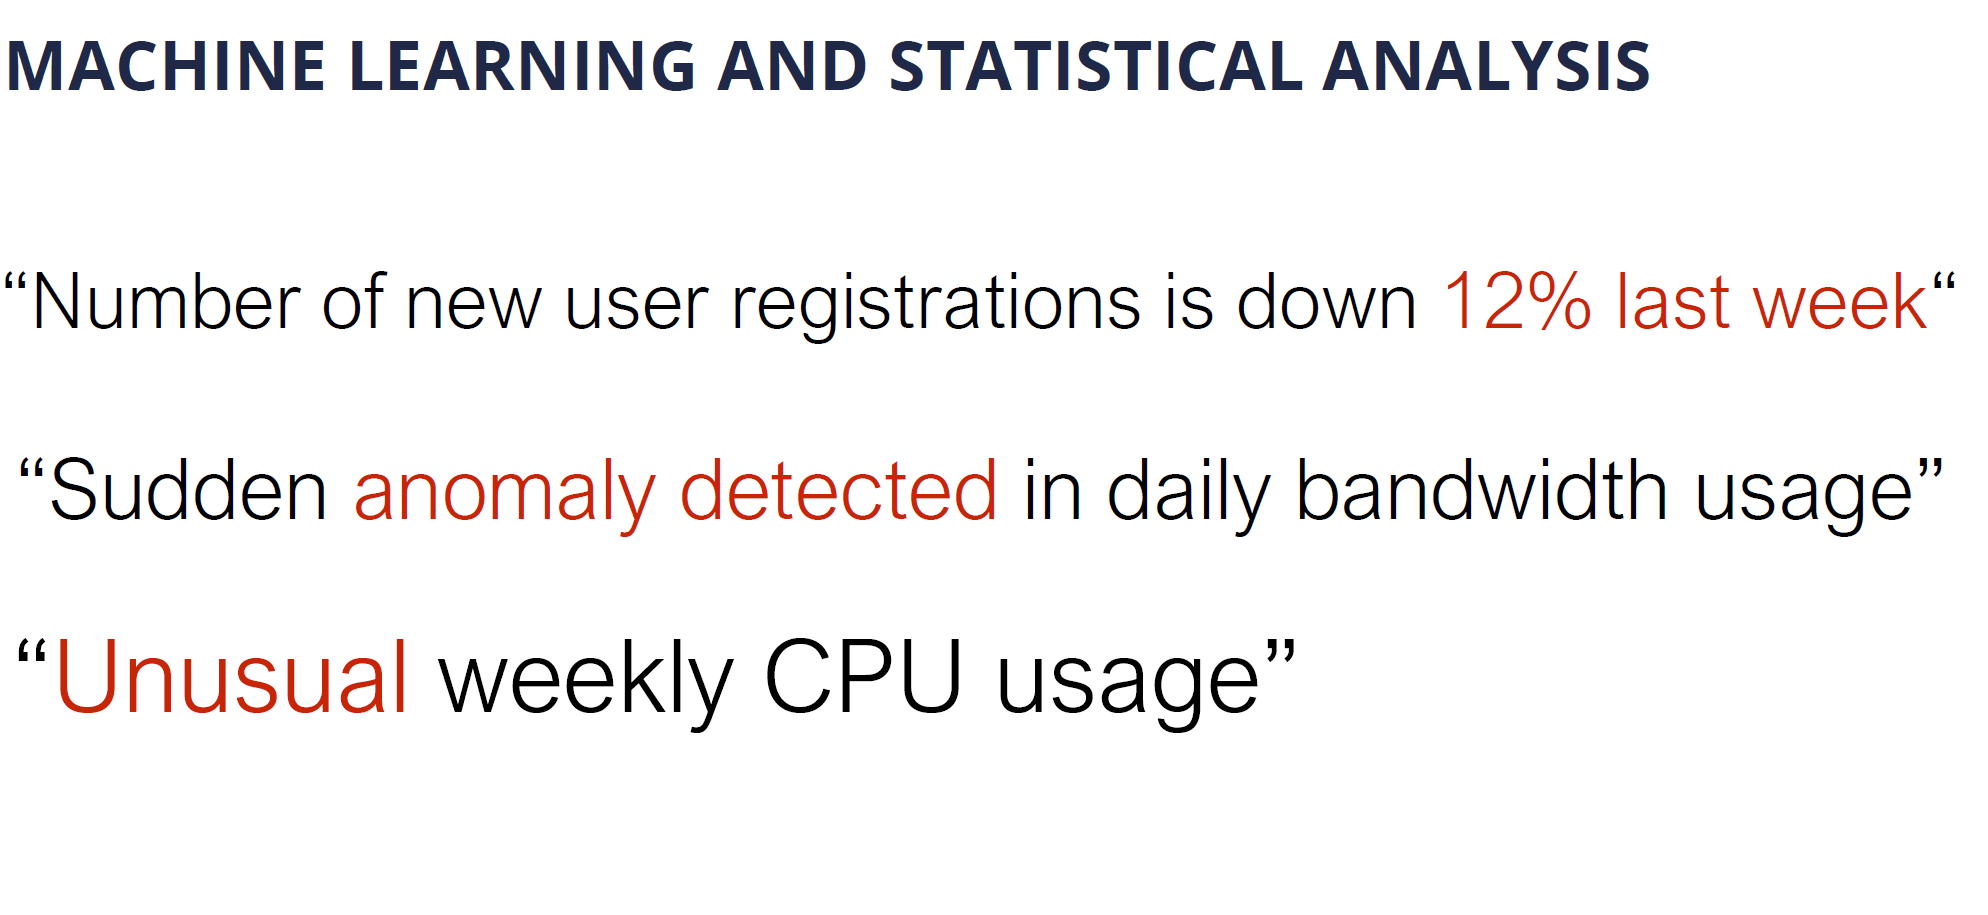
Defining static trigger thresholds is a relatively simple task, but it doesn’t scale too well in dynamic environments. With Machine Learning and Statistical Analysis, we can analyze our data trends and perform anomaly detection. This has been greatly extended in Zabbix 6.0 LTS with Anomaly Detection and Baseline Monitoring functionality.

Zabbix 6.0 Adds an extended set of functions for trend analysis and trend prediction. These support multiple flexible parameters, such as the ability to define seasonality for your data analysis. This is another way how to get additional insights out of the data collected by Zabbix

More value to users

When I think about the direction that Zabbix is headed in, and look at the Zabbix roadmap, one of the main questions I ask is “How can we deliver more value to our enterprise users?”

In Zabbix 6.0 LTS we made some major steps to make Zabbix fit not only for infrastructure monitoring but also fit for Business Service monitoring – the monitoring of services that we provide for our end-users or internal company users. Zabbix 6.0 LTS comes with complex service level object definitions, real-time SLA reporting, multi-tenancy options, Business Service alerting options, and root cause and Impact analysis.

New visualization capabilities

It is important to present the collected data in a human-readable way. That’s why we invest a lot of time and effort in order to improve the native visualization capabilities. In Zabbix 6.0 LTS we have introduced Geographical Maps together with additional widgets for TOP N reporting and templated and multi-page dashboards.

The introduction of reports in Zabbix 5.2 allowed our users to leverage their Zabbix Dashboards to generate scheduled PDF reports with respect to user permissions. Our users can generate daily, weekly, monthly or yearly reports and send them to their infrastructure administrators or customers.

IoT monitoring

With the introduction of support for Modbus and MQTT protocols, Zabbix can be used to monitor IoT devices and obtain environmental information from different sensors such as temperature, humidity, and more. In addition, Zabbix can now be used to monitor factory equipment, building management systems, IoT gateways, and more.

Infrastructure as a code

With IT infrastructures growing in scale, automation is more important than ever. For this reason, many companies prefer preserving and deploying their infrastructure as code. With the support of YAML format for our templates, you can now keep them in a git repository and by utilizing CI/CD tools you can now deploy your templates automatically.

This enables our users to manage their templates in a central location – the git repository, which helps users to perform change management and versioning and then deploy the template to Zabbix by using CI/CD tools.

Tags for classification

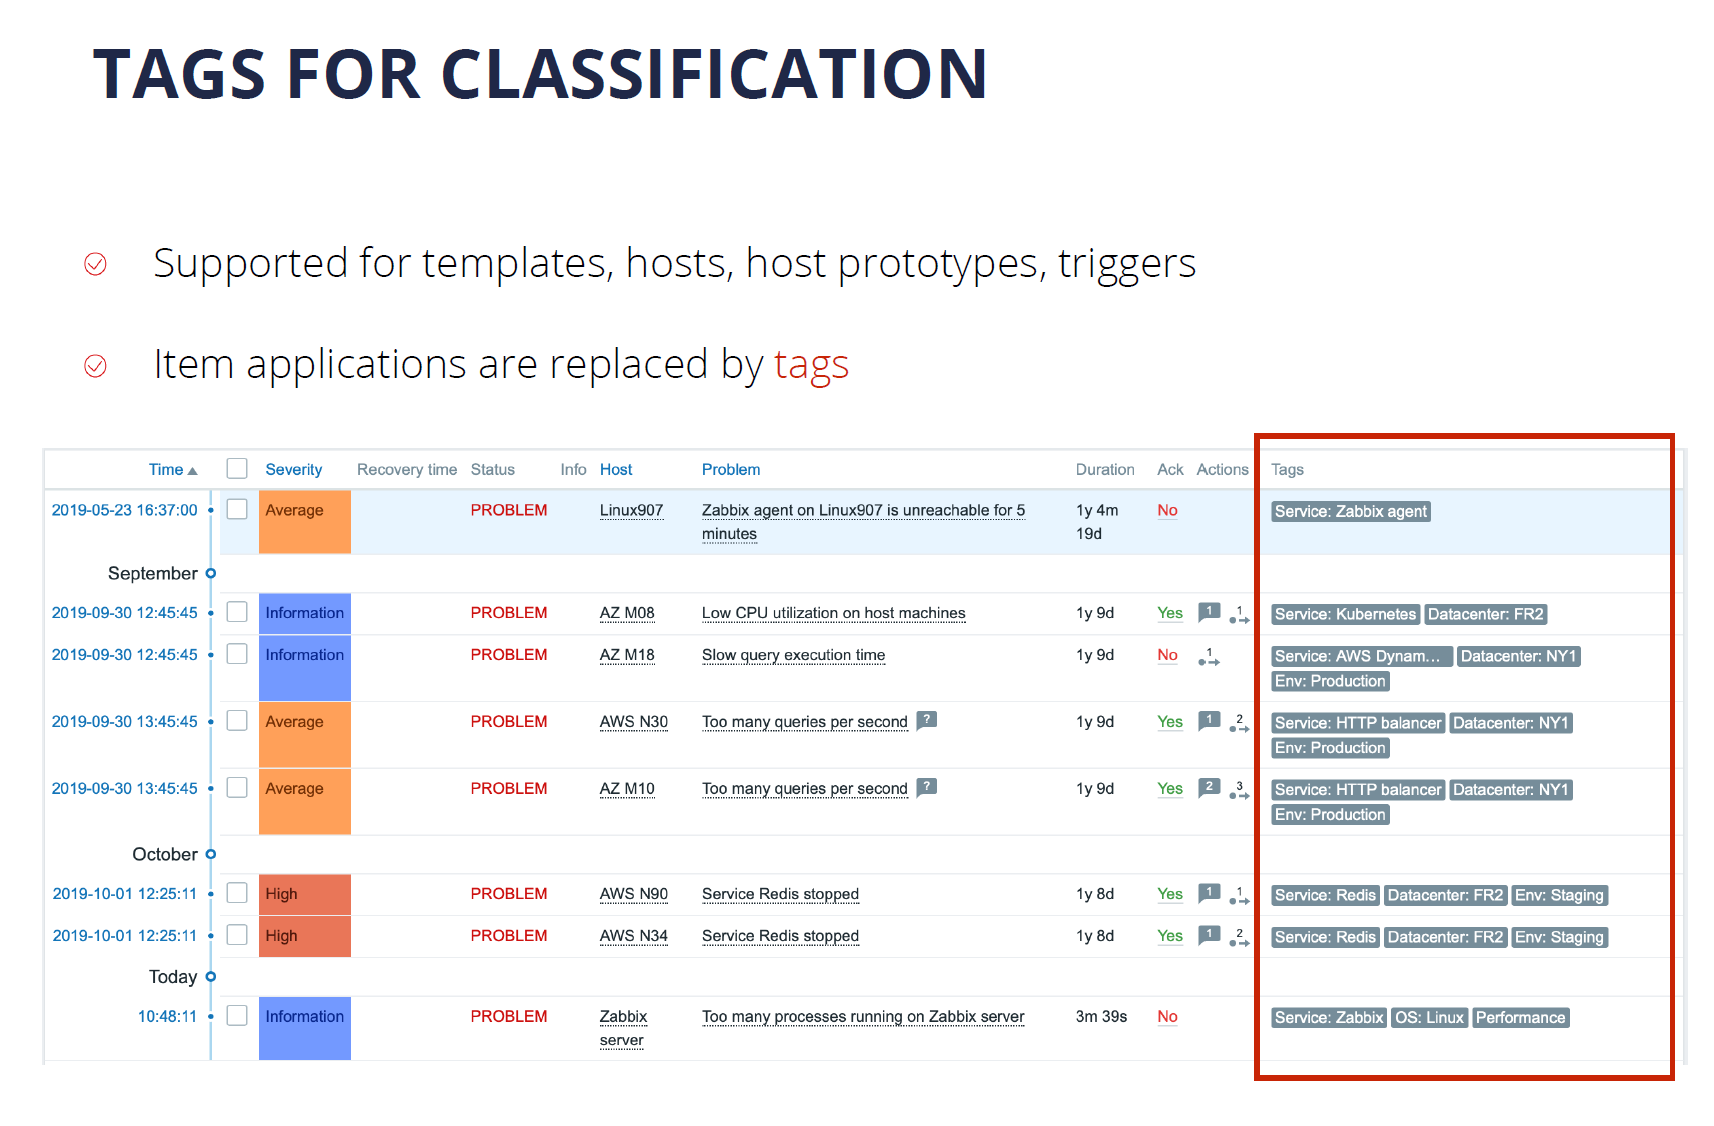
Over the past few versions, we have made a major push to support tags for most Zabbix entities. The switch from applications to tags in Zabbix 5.4 made the tool much more flexible. Tags can now be used for the classification of items, triggers, hosts, business services. The tags that the users define can also be used in alerting, filtering, and reporting.

What’s next?

You’re probably wondering – what’s coming next? What are the main vectors for the future development of Zabbix?

First off – we will continue to invest in usability. While the tool is made by professionals for professionals, it is important for us to make using the tool as easy as possible. Improvements to the Zabbix Frontend, general usability, and UX can be expected very soon.

We plan to continue to invest in the visualization and reporting capabilities of Zabbix. We want all data collected by our monitoring tool to provide information in a single pane of glass. This way our users can see the full picture of their environment while also seeing the root cause analysis for the ongoing problems that we face. This way we can get most of the data that Zabbix collects.

Extending the scope of monitoring is an ongoing process for us. We would like to implement additional features for compliance monitoring. I think that we will be able to introduce a solution for application performance monitoring very soon. We’d like to make log monitoring more powerful and comprehensive. monitoring of public and private clouds is also very important for us, given the current IT paradigms.

We’d like to make sure that Zabbix is absolutely extendable on all levels. While we can already extend Zabbix with different types of plugins, webhooks, and UI modules there’s more to come in the near future.

The topic of high availability, scalability, and load balancing is extremely important to us. We will continue building on the existing foundations to make Zabbix a truly cloud-native solution.

Advanced event correlation engine

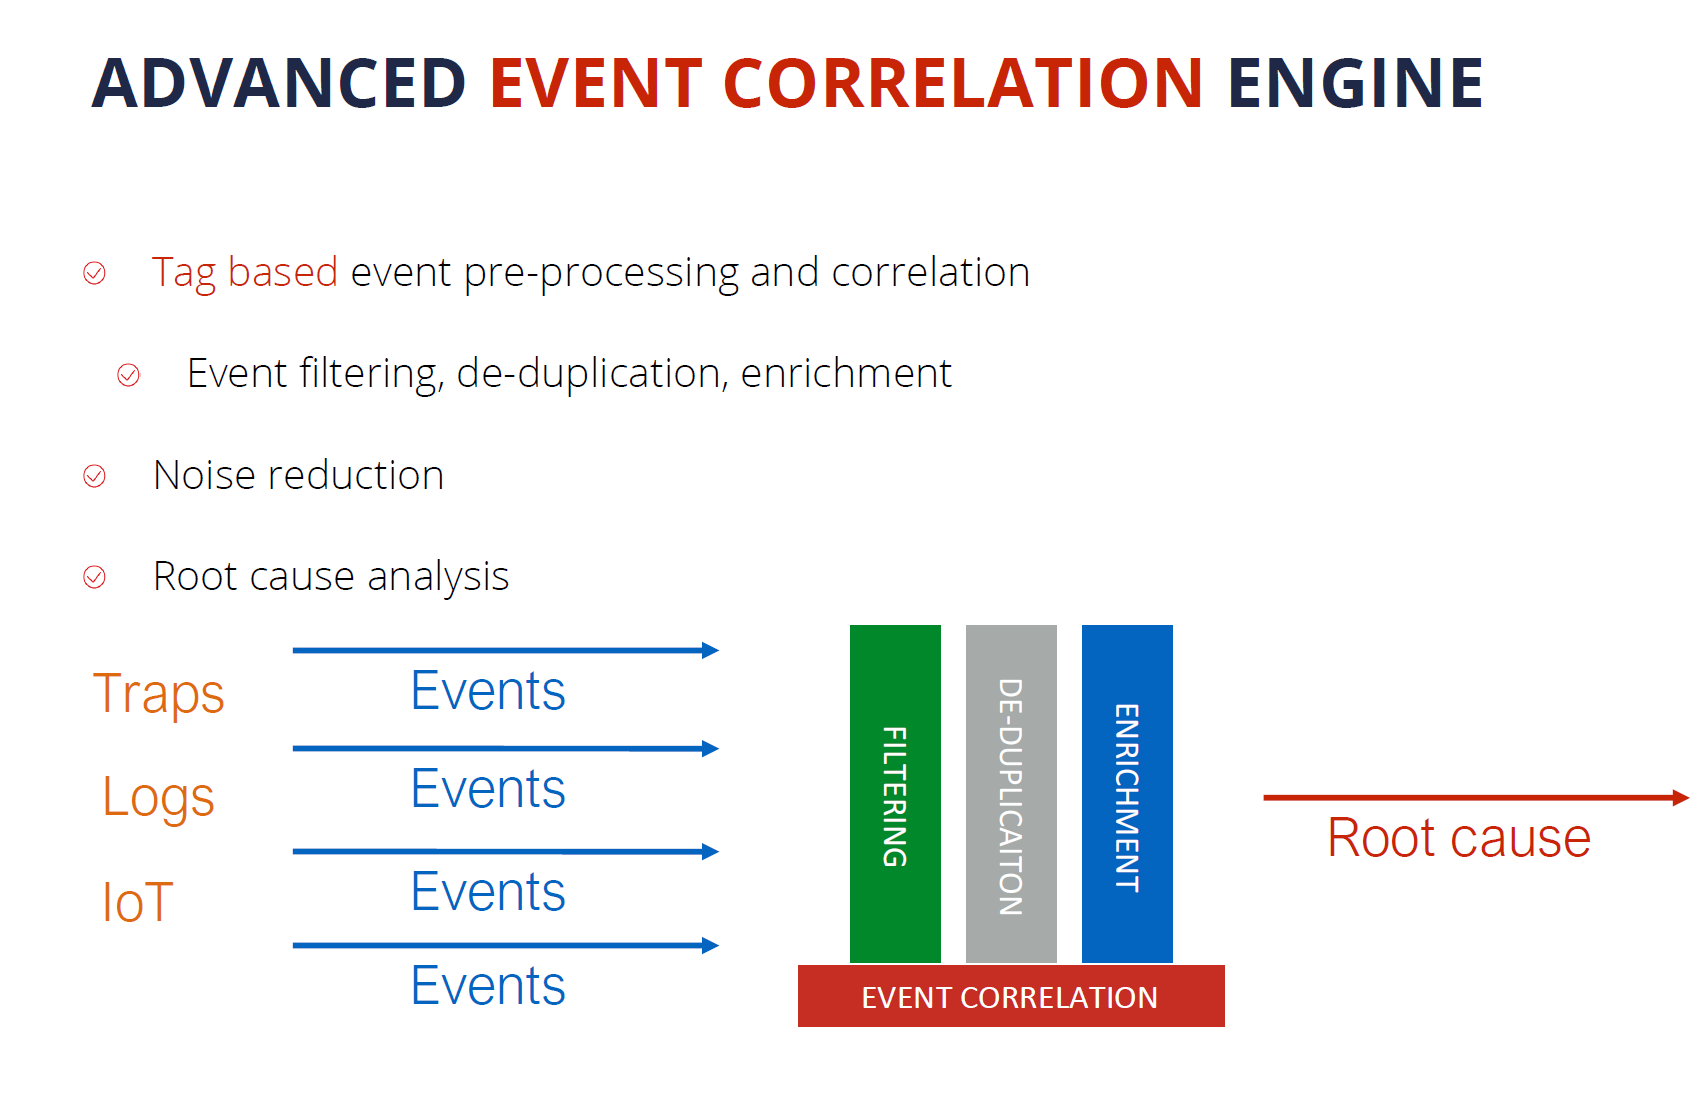
Advanced event processing is a really important topic. When we talk about a monitoring solution, we pay very much attention to the number of metrics that we are collecting. We mustn’t forget, that for large-scale environments the number of events that we generate based on those metrics is also extremely important. We need to keep control and manage the ever-growing number of different events coming from different sources. This is why we would like to focus on noise reduction, specifically – root cause analysis.

For this reason, we can expect Zabbix to introduce an advanced event correlation model in the future. This model should have the ability to filter and deduplicate the events as well as perform event enrichment, thus leading to a much better root cause analysis.

Multi DC Monitoring

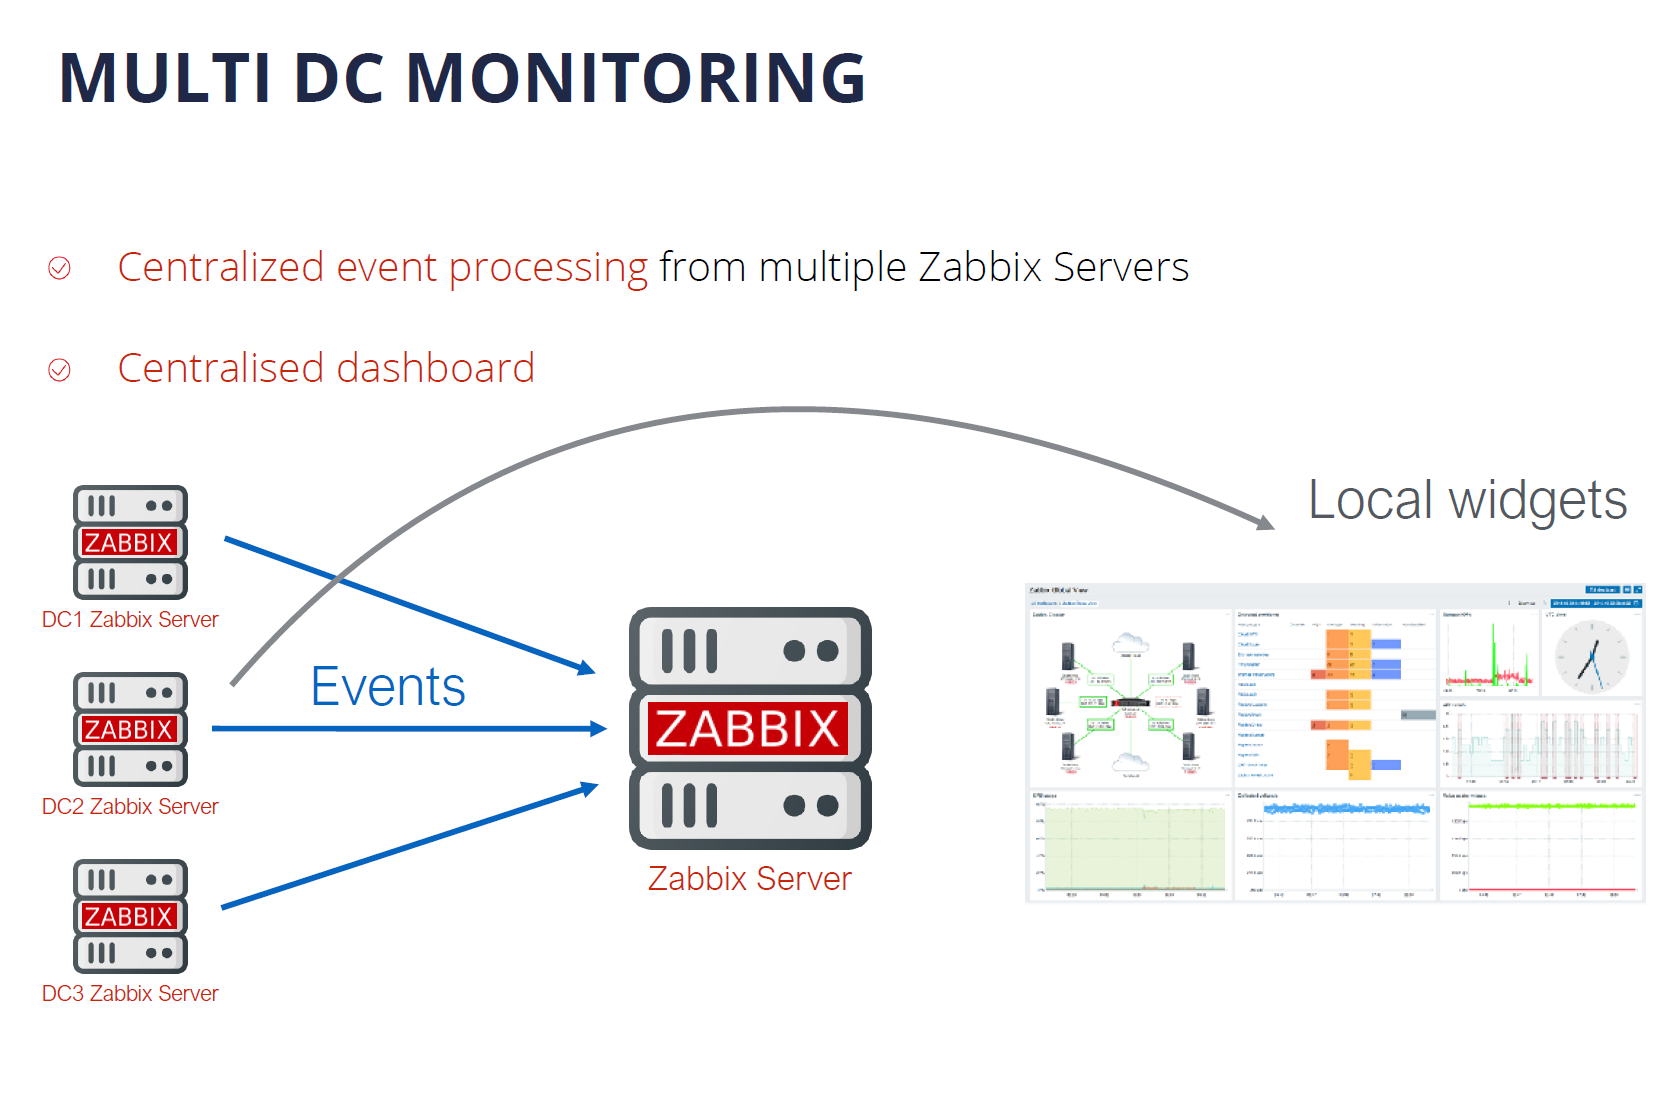
Currently, Multi DC monitoring can be done with Zabbix by deploying a distributed Zabbix instance that utilizes Zabbix proxies. But there are use cases, where it would be more beneficial to have multiple Zabbix servers deployed across different datacenters – all reporting to a single location for centralized event processing, centralized visualization, and reporting as well as centralized dashboards. This is something that is coming soon to Zabbix.

Zabbix Release Schedule

Of course, the burning question is – when is Zabbix 6.0 LTS going to be released? And we are very close to finalizing the next LTS release. I would expect Zabbix 6.0 LTS to be officially released in January 2022.

As for Zabbix 6.2 and 6.4 – these releases are still planned for Q2 and Q4, 2022. The next LTS release – Zabbix 7.0 LTS is planned to be released in Q2, 2023.

Zabbix Roadmap

If you want to follow the development of Zabbix – we have a special page just for that – the Zabbix Roadmap. Here you can find up-to-date information about the development plans for Zabbix 6.2, 6.4, and 7.0 LTS. The Roadmap also represents the current development status of Zabbix 6.0 LTS.

Questions

Q: What would you say is the main benefit of why users should migrate from Zabbix 5.0/4.0 or older versions to 6.0 LTS?

A: I think that Zabbix 6.0 LTS is a very different product – even when you compare it with the relatively recent Zabbix 5.0 LTS. It comes with many improvements, some of which I mentioned here in my keynote. For example, Business Service monitoring provides huge added value to enterprise customers.

With the new trigger syntax and the new functions related to anomaly detection and baseline monitoring our users can get much more out of the data that they already have in their monitoring tool.

The new visualization options – multiple new widgets, geographical maps, scheduled PDF reporting provide a lot of added value to our end-users and to their customers as well.

Q: Any plans to make changes on the Zabbix DB backend level – make it more scaleable or completely redesign it?

A: Right now we keep all of our information in a relational database such as MySQL or PostgreSQL. We have added the support for TimescaleDB which brings some huge advantages to our users, thanks to improved data storage and performance efficiency.

But we still have users that wish to connect different storage engines to Zabbix – maybe specifically optimized to keep time-series data. Actually, this is already on our roadmap. Our plan is to introduce a unified API for historical data so that if you wish to attach your own storage, we just have to deploy a plugin that will communicate both with our historical API and also talk to the storage engine of your choosing. This feature is coming and is already on our Roadmap.

Q: What is your personal favorite feature? Something that you 100% wanted to see implemented in Zabbix 6.0 LTS?

A: I see Zabbix 6.0 LTS as a combination of Zabbix 5.2, 5.4, and finally the features introduced directly in Zabbix 6.0 LTS. Personally, I think that my favorite features in Zabbix 6.0 LTS are features that make up the latest implementation of Anomaly detection.

We could be at the very beginning of exploring more advanced machine learning and statistical analysis capabilities, but I’m pretty sure that with every new release of Zabbix there will be new features related to machine learning, anomaly detection, and trend prediction.

This could provide a way for Zabbix to generate and share insights with our users. Analysis of what’s happening with your system, with your metrics – how the metrics in your system behave.
Snapshots from the history of AI, plus AI education resources

Post Syndicated from Janina Ander original https://www.raspberrypi.org/blog/machine-learning-education-snapshots-history-ai-hello-world-12/

In Hello World issue 12, our free magazine for computing educators, George Boukeas, DevOps Engineer for the Astro Pi Challenge here at the Foundation, introduces big moments in the history of artificial intelligence (AI) to share with your learners:

The story of artificial intelligence (AI) is a story about humans trying to understand what makes them human. Some of the episodes in this story are fascinating. These could help your learners catch a glimpse of what this field is about and, with luck, compel them to investigate further.                   

The imitation game

In 1950, Alan Turing published a philosophical essay titled Computing Machinery and Intelligence, which started with the words: “I propose to consider the question: Can machines think?” Yet Turing did not attempt to define what it means to think. Instead, he suggested a game as a proxy for answering the question: the imitation game. In modern terms, you can imagine a human interrogator chatting online with another human and a machine. If the interrogator does not successfully determine which of the other two is the human and which is the machine, then the question has been answered: this is a machine that can think.

A statue of Alan Turing on a park bench in Manchester.
The Alan Turing Memorial in Manchester

This imitation game is now a fiercely debated benchmark of artificial intelligence called the Turing test. Notice the shift in focus that Turing suggests: thinking is to be identified in terms of external behaviour, not in terms of any internal processes. Humans are still the yardstick for intelligence, but there is no requirement that a machine should think the way humans do, as long as it behaves in a way that suggests some sort of thinking to humans.

In his essay, Turing also discusses learning machines. Instead of building highly complex programs that would prescribe every aspect of a machine’s behaviour, we could build simpler programs that would prescribe mechanisms for learning, and then train the machine to learn the desired behaviour. Turing’s text provides an excellent metaphor that could be used in class to describe the essence of machine learning: “Instead of trying to produce a programme to simulate the adult mind, why not rather try to produce one which simulates the child’s? If this were then subjected to an appropriate course of education one would obtain the adult brain. We have thus divided our problem into two parts: the child-programme and the education process.”

A chess board with two pieces of each colour left.
Chess was among the games that early AI researchers like Alan Turing developed algorithms for.

It is remarkable how Turing even describes approaches that have since been evolved into established machine learning methods: evolution (genetic algorithms), punishments and rewards (reinforcement learning), randomness (Monte Carlo tree search). He even forecasts the main issue with some forms of machine learning: opacity. “An important feature of a learning machine is that its teacher will often be very largely ignorant of quite what is going on inside, although he may still be able to some extent to predict his pupil’s behaviour.”

The evolution of a definition

The term ‘artificial intelligence’ was coined in 1956, at an event called the Dartmouth workshop. It was a gathering of the field’s founders, researchers who would later have a huge impact, including John McCarthy, Claude Shannon, Marvin Minsky, Herbert Simon, Allen Newell, Arthur Samuel, Ray Solomonoff, and W.S. McCulloch.   

Go has vastly more possible moves than chess, and was thought to remain out of the reach of AI for longer than it did.

The simple and ambitious definition for artificial intelligence, included in the proposal for the workshop, is illuminating: ‘making a machine behave in ways that would be called intelligent if a human were so behaving’. These pioneers were making the assumption that ‘every aspect of learning or any other feature of intelligence can in principle be so precisely described that a machine can be made to simulate it’. This assumption turned out to be patently false and led to unrealistic expectations and forecasts. Fifty years later, McCarthy himself stated that ‘it was harder than we thought’.

Modern definitions of intelligence are of distinctly different flavour than the original one: ‘Intelligence is the quality that enables an entity to function appropriately and with foresight in its environment’ (Nilsson). Some even speak of rationality, rather than intelligence: ‘doing the right thing, given what it knows’ (Russell and Norvig).

A computer screen showing a complicated graph.
The amount of training data AI developers have access to has skyrocketed in the past decade.

Read the whole of this brief history of AI in Hello World #12

In the full article, which you can read in the free PDF copy of the issue, George looks at:

  • Early advances researchers made from the 1950s onwards while developing games algorithms, e.g. for chess.
  • The 1997 moment when Deep Blue, a purpose-built IBM computer, beating chess world champion Garry Kasparov using a search approach.
  • The 2011 moment when Watson, another IBM computer system, beating two human Jeopardy! champions using multiple techniques to answer questions posed in natural language.
  • The principles behind artificial neural networks, which have been around for decades and are now underlying many AI/machine learning breakthroughs because of the growth in computing power and availability of vast datasets for training.
  • The 2017 moment when AlphaGo, an artificial neural network–based computer program by Alphabet’s DeepMind, beating Ke Jie, the world’s top-ranked Go player at the time.
Stacks of server hardware behind metal fencing in a data centre.
Machine learning systems need vast amounts of training data, the collection and storage of which has only become technically possible in the last decade.

More on machine learning and AI education in Hello World #12

In your free PDF of Hello World issue 12, you’ll also find:

  • An interview with University of Cambridge statistician David Spiegelhalter, whose work shaped some of the foundations of AI, and who shares his thoughts on data science in schools and the limits of AI 
  • An introduction to Popbots, an innovative project by MIT to open AI to the youngest learners
  • An article by Ken Kahn, researcher in the Department of Education at the University of Oxford, on using the block-based Snap! language to introduce your learners to natural language processing
  • Unplugged and online machine learning activities for learners age 7 to 16 in the regular ‘Lesson plans’ section
  • And lots of other relevant articles

You can also read many of these articles online on the Hello World website.

Find more resources for AI and data science education

In Hello World issue 16, the focus is on all things data science and data literacy for your learners. As always, you can download a free copy of the issue. And on our Hello World podcast, we chat with practicing computing educators about how they bring AI, AI ethics, machine learning, and data science to the young people they teach.

If you want a practical introduction to the basics of machine learning and how to use it, take our free online course.

Drawing of a machine learning ars rover trying to decide whether it is seeing an alien or a rock.

There are still many open questions about what good AI and data science education looks like for young people. To learn more, you can watch our panel discussion about the topic, and join our monthly seminar series to hear insights from computing education researchers around the world.

We are also collating a growing list of educational resources about these topics based on our research seminars, seminar participants’ recommendations, and our own work. Find the resource list here.

The post Snapshots from the history of AI, plus AI education resources appeared first on Raspberry Pi.

Summary of Zabbix Summit Online 2021, Zabbix 6.0 LTS release date and Zabbix Workshops

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/summary-of-zabbix-summit-online-2021-zabbix-6-0-lts-release-date-and-zabbix-workshops/17155/

Now that the Zabbix Summit Online 2021 has concluded, we are thrilled to report we hosted attendees from over 3000 organizations from more than 130 countries all across the globe.

This year, the main focus of the speeches was the upcoming Zabbix 6.0 LTS release, as well as speeches focused on automating Zabbix data collection and configuration, Integrating Zabbix within existing company infrastructures, and migrating from legacy tools to Zabbix. 21 speakers in total presented their use cases and talked about new Zabbix features during the Summit with over 8 hours of content.

In case you missed the Summit or wish to come back to some of the speeches – both the presentations (in PDF format) and the videos of the speeches are available on the Zabbix Summit Online 2021 Event page.

Zabbix 6.0 LTS release date

As for Zabbix 6.0 LTS – as per our statement during the event, you can expect Zabbix 6.0 LTS to release in early 2022. At the time of this post, the latest pre-release version is Zabbix 6.0 Alpha 7, with the first Beta version scheduled for release VERY soon. Feel free to deploy the latest pre-release version and take a look at features such as Geomaps, Business Service monitoring, improved Audit log, UX improvements, Anomaly detection with Machine Learning, and more! The list of the latest released Zabbix 6.0 versions as well as the improvements and fixes they contain is available in the Release notes section of our website.

Zabbix 6.0 LTS Workshops

The workshops will focus on particular Zabbix 6.0 LTS features and will be available once the Zabbix 6.0 LTS is released. The workshops will provide a unique chance to learn and practice the configuration of specific Zabbix 6.0 LTS features under the guidance of a certified Zabbix trainer at absolutely no cost! Some of the topics covered in the workshops will include – Deploying Zabbix server HA cluster, Creating triggers for Baseline monitoring and Anomaly detection, Displaying your infrastructure status on Geomaps, Deploying Business Service monitoring with root cause analysis, and more!

Upcoming events

But there’s more! On December 9 2021 Zabbix will host PostgreSQL Monitoring Day with Zabbix & Postgres Pro. The speeches will focus on monitoring PostgreSQL databases, running Zabbix on PostgreSQL DB backends with TimescaleDB, and securing your Zabbix + PostgreSQL instances. If you’re currently using PostgreSQL DB backends r plan to do so in the future – you definitely don’t want to miss out!

As for 2022 – you can expect multiple meetups regarding Zabbix 6.0 LTS features and use cases, as well as events focused on specific monitoring use cases. More information will be publicly available with the release of Zabbix 6.0 LTS.

How do we develop AI education in schools? A panel discussion

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/ai-education-schools-panel-uk-policy/

AI is a broad and rapidly developing field of technology. Our goal is to make sure all young people have the skills, knowledge, and confidence to use and create AI systems. So what should AI education in schools look like?

To hear a range of insights into this, we organised a panel discussion as part of our seminar series on AI and data science education, which we co-host with The Alan Turing Institute. Here our panel chair Tabitha Goldstaub, Co-founder of CogX and Chair of the UK government’s AI Council, summarises the event. You can also watch the recording below.

As part of the Raspberry Pi Foundation’s monthly AI education seminar series, I was delighted to chair a special panel session to broaden the range of perspectives on the subject. The members of the panel were:

  • Chris Philp, UK Minister for Tech and the Digital Economy
  • Philip Colligan, CEO of the Raspberry Pi Foundation 
  • Danielle Belgrave, Research Scientist, DeepMind
  • Caitlin Glover, A level student, Sandon School, Chelmsford
  • Alice Ashby, student, University of Brighton

The session explored the UK government’s commitment in the recently published UK National AI Strategy stating that “the [UK] government will continue to ensure programmes that engage children with AI concepts are accessible and reach the widest demographic.” We discussed what it will take to make this a reality, and how we will ensure young people have a seat at the table.

Two teenage girls do coding during a computer science lesson.

Why AI education for young people?

It was clear that the Minister felt it is very important for young people to understand AI. He said, “The government takes the view that AI is going to be one of the foundation stones of our future prosperity and our future growth. It’s an enabling technology that’s going to have almost universal applicability across our entire economy, and that is why it’s so important that the United Kingdom leads the world in this area. Young people are the country’s future, so nothing is complete without them being at the heart of it.”

A teacher watches two female learners code in Code Club session in the classroom.

Our panelist Caitlin Glover, an A level student at Sandon School, reiterated this from her perspective as a young person. She told us that her passion for AI started initially because she wanted to help neurodiverse young people like herself. Her idea was to start a company that would build AI-powered products to help neurodiverse students.

What careers will AI education lead to?

A theme of the Foundation’s seminar series so far has been how learning about AI early may impact young people’s career choices. Our panelist Alice Ashby, who studies Computer Science and AI at Brighton University, told us about her own process of deciding on her course of study. She pointed to the fact that terms such as machine learning, natural language processing, self-driving cars, chatbots, and many others are currently all under the umbrella of artificial intelligence, but they’re all very different. Alice thinks it’s hard for young people to know whether it’s the right decision to study something that’s still so ambiguous.

A young person codes at a Raspberry Pi computer.

When I asked Alice what gave her the courage to take a leap of faith with her university course, she said, “I didn’t know it was the right move for me, honestly. I took a gamble, I knew I wanted to be in computer science, but I wanted to spice it up.” The AI ecosystem is very lucky that people like Alice choose to enter the field even without being taught what precisely it comprises.

We also heard from Danielle Belgrave, a Research Scientist at DeepMind with a remarkable career in AI for healthcare. Danielle explained that she was lucky to have had a Mathematics teacher who encouraged her to work in statistics for healthcare. She said she wanted to ensure she could use her technical skills and her love for math to make an impact on society, and to really help make the world a better place. Danielle works with biologists, mathematicians, philosophers, and ethicists as well as with data scientists and AI researchers at DeepMind. One possibility she suggested for improving young people’s understanding of what roles are available was industry mentorship. Linking people who work in the field of AI with school students was an idea that Caitlin was eager to confirm as very useful for young people her age.

We need investment in AI education in school

The AI Council’s Roadmap stresses how important it is to not only teach the skills needed to foster a pool of people who are able to research and build AI, but also to ensure that every child leaves school with the necessary AI and data literacy to be able to become engaged, informed, and empowered users of the technology. During the panel, the Minister, Chris Philp, spoke about the fact that people don’t have to be technical experts to come up with brilliant ideas, and that we need more people to be able to think creatively and have the confidence to adopt AI, and that this starts in schools. 

A class of primary school students do coding at laptops.

Caitlin is a perfect example of a young person who has been inspired about AI while in school. But sadly, among young people and especially girls, she’s in the minority by choosing to take computer science, which meant she had the chance to hear about AI in the classroom. But even for young people who choose computer science in school, at the moment AI isn’t in the national Computing curriculum or part of GCSE computer science, so much of their learning currently takes place outside of the classroom. Caitlin added that she had had to go out of her way to find information about AI; the majority of her peers are not even aware of opportunities that may be out there. She suggested that we ensure AI is taught across all subjects, so that every learner sees how it can make their favourite subject even more magical and thinks “AI’s cool!”.

A primary school boy codes at a laptop with the help of an educator.

Philip Colligan, the CEO here at the Foundation, also described how AI could be integrated into existing subjects including maths, geography, biology, and citizenship classes. Danielle thoroughly agreed and made the very good point that teaching this way across the school would help prepare young people for the world of work in AI, where cross-disciplinary science is so important. She reminded us that AI is not one single discipline. Instead, many different skill sets are needed, including engineering new AI systems, integrating AI systems into products, researching problems to be addressed through AI, or investigating AI’s societal impacts and how humans interact with AI systems.

On hearing about this multitude of different skills, our discussion turned to the teachers who are responsible for imparting this knowledge, and to the challenges they face. 

The challenge of AI education for teachers

When we shifted the focus of the discussion to teachers, Philip said: “If we really want to equip every young person with the knowledge and skills to thrive in a world that shaped by these technologies, then we have to find ways to evolve the curriculum and support teachers to develop the skills and confidence to teach that curriculum.”

Teenage students and a teacher do coding during a computer science lesson.

I asked the Minister what he thought needed to happen to ensure we achieved data and AI literacy for all young people. He said, “We need to work across government, but also across business and society more widely as well.” He went on to explain how important it was that the Department for Education (DfE) gets the support to make the changes needed, and that he and the Office for AI were ready to help.

Philip explained that the Raspberry Pi Foundation is one of the organisations in the consortium running the National Centre for Computing Education (NCCE), which is funded by the DfE in England. Through the NCCE, the Foundation has already supported thousands of teachers to develop their subject knowledge and pedagogy around computer science.

A recent study recognises that the investment made by the DfE in England is the most comprehensive effort globally to implement the computing curriculum, so we are starting from a good base. But Philip made it clear that now we need to expand this investment to cover AI.

Young people engaging with AI out of school

Philip described how brilliant it is to witness young people who choose to get creative with new technologies. As an example, he shared that the Foundation is seeing more and more young people employ machine learning in the European Astro Pi Challenge, where participants run experiments using Raspberry Pi computers on board the International Space Station. 

Three teenage boys do coding at a shared computer during a computer science lesson.

Philip also explained that, in the Foundation’s non-formal CoderDojo club network and its Coolest Projects tech showcase events, young people build their dream AI products supported by volunteers and mentors. Among these have been autonomous recycling robots and AI anti-collision alarms for bicycles. Like Caitlin with her company idea, this shows that young people are ready and eager to engage and create with AI.

We closed out the panel by going back to a point raised by Mhairi Aitken, who presented at the Foundation’s research seminar in September. Mhairi, an Alan Turing Institute ethics fellow, argues that children don’t just need to learn about AI, but that they should actually shape the direction of AI. All our panelists agreed on this point, and we discussed what it would take for young people to have a seat at the table.

A Black boy uses a Raspberry Pi computer at school.

Alice advised that we start by looking at our existing systems for engaging young people, such as Youth Parliament, student unions, and school groups. She also suggested adding young people to the AI Council, which I’m going to look into right away! Caitlin agreed and added that it would be great to make these forums virtual, so that young people from all over the country could participate.

The panel session was full of insight and felt very positive. Although the challenge of ensuring we have a data- and AI-literate generation of young people is tough, it’s clear that if we include them in finding the solution, we are in for a bright future. 

What’s next for AI education at the Raspberry Pi Foundation?

In the coming months, our goal at the Foundation is to increase our understanding of the concepts underlying AI education and how to teach them in an age-appropriate way. To that end, we will start to conduct a series of small AI education research projects, which will involve gathering the perspectives of a variety of stakeholders, including young people. We’ll make more information available on our research pages soon.

In the meantime, you can sign up for our upcoming research seminars on AI and data science education, and peruse the collection of related resources we’ve put together.

The post How do we develop AI education in schools? A panel discussion appeared first on Raspberry Pi.

The machine learning effect: Magic boxes and computational thinking 2.0

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/machine-learning-education-school-computational-thinking-2-0-research-seminar/

How does teaching children and young people about machine learning (ML) differ from teaching them about other aspects of computing? Professor Matti Tedre and Dr Henriikka Vartiainen from the University of Eastern Finland shared some answers at our latest research seminar.

Three smiling young learners in a computing classroom.
We need to determine how to teach young people about machine learning, and what teachers need to know to help their learners form correct mental models.

Their presentation, titled ‘ML education for K-12: emerging trajectories’, had a profound impact on my thinking about how we teach computational thinking and programming. For this blog post, I have simplified some of the complexity associated with machine learning for the benefit of readers who are new to the topic.

a 3D-rendered grey box.
Machine learning is not magic — what needs to change in computing education to make sure learners don’t see ML systems as magic boxes?

Our seminars on teaching AI, ML, and data science

We’re currently partnering with The Alan Turing Institute to host a series of free research seminars about how to teach artificial intelligence (AI) and data science to young people.

The seminar with Matti and Henriikka, the third one of the series, was very well attended. Over 100 participants from San Francisco to Rajasthan, including teachers, researchers, and industry professionals, contributed to a lively and thought-provoking discussion.

Representing a large interdisciplinary team of researchers, Matti and Henriikka have been working on how to teach AI and machine learning for more than three years, which in this new area of study is a long time. So far, the Finnish team has written over a dozen academic papers based on their pilot studies with kindergarten-, primary-, and secondary-aged learners.

Current teaching in schools: classical rule-driven programming

Matti and Henriikka started by giving an overview of classical programming and how it is currently taught in schools. Classical programming can be described as rule-driven. Example features of classical computer programs and programming languages are:

  • A classical language has a strict syntax, and a limited set of commands that can only be used in a predetermined way
  • A classical language is deterministic, meaning we can guarantee what will happen when each line of code is run
  • A classical program is executed in a strict, step-wise order following a known set of rules

When we teach this type of programming, we show learners how to use a deductive problem solving approach or workflow: defining the task, designing a possible solution, and implementing the solution by writing a stepwise program that is then run on a computer. We encourage learners to avoid using trial and error to write programs. Instead, as they develop and test a program, we ask them to trace it line by line in order to predict what will happen when each line is run (glass-box testing).

A list of features of rule-driven computer programming, also included in the text.
The features of classical (rule-driven) programming approaches as taught in computer science education (CSE) (Tedre & Vartiainen, 2021).

Classical programming underpins the current view of computational thinking (CT). Our speakers called this version of CT ‘CT 1.0’. So what’s the alternative Matti and Henriikka presented, and how does it affect what computational thinking is or may become?

Machine learning (data-driven) models and new computational thinking (CT 2.0) 

Rule-based programming languages are not being eradicated. Instead, software systems are being augmented through the addition of machine learning (data-driven) elements. Many of today’s successful software products, such as search engines, image classifiers, and speech recognition programs, combine rule-driven software and data-driven models. However, the workflows for these two approaches to solving problems through computing are very different.

A table comparing problem solving workflows using computational thinking 1.0 versus computational thinking 2.0, info also included in the text.
Problem solving is very different depending on whether a rule-driven computational thinking (CT 1.0) approach or a data-driven computational thinking (CT 2.0) approach is used (Tedre & Vartiainen,2021).

Significantly, while in rule-based programming (and CT 1.0), the focus is on solving problems by creating algorithms, in data-driven approaches, the problem solving workflow is all about the data. To highlight the profound impact this shift in focus has on teaching and learning computing, Matti introduced us to a new version of computational thinking for machine learning, CT 2.0, which is detailed in a forthcoming research paper.

Because of the focus on data rather than algorithms, developing a machine learning model is not at all like developing a classical rule-driven program. In classical programming, programs can be traced, and we can predict what will happen when they run. But in data-driven development, there is no flow of rules, and no absolutely right or wrong answer.

A table comparing conceptual differences between computational thinking 1.0 versus computational thinking 2.0, info also included in the text.
There are major differences between rule-driven computational thinking (CT 1.0) and data-driven computational thinking (CT 2.0), which impact what computing education needs to take into account (Tedre & Vartiainen,2021).

Machine learning models are created iteratively using training data and must be cross-validated with test data. A tiny change in the data provided can make a model useless. We rarely know exactly why the output of an ML model is as it is, and we cannot explain each individual decision that the model might have made. When evaluating a machine learning system, we can only say how well it works based on statistical confidence and efficiency. 

Machine learning education must cover ethical and societal implications 

The ethical and societal implications of computer science have always been important for students to understand. But machine learning models open up a whole new set of topics for teachers and students to consider, because of these models’ reliance on large datasets, the difficulty of explaining their decisions, and their usefulness for automating very complex processes. This includes privacy, surveillance, diversity, bias, job losses, misinformation, accountability, democracy, and veracity, to name but a few.

I see the shift in problem solving approach as a chance to strengthen the teaching of computing in general, because it opens up opportunities to teach about systems, uncertainty, data, and society.

Jane Waite

Teaching machine learning: the challenges of magic boxes and new mental models

For teaching classical rule-driven programming, much time and effort has been put into researching learners’ understanding of what a program will do when it is run. This kind of understanding is called a learner’s mental model or notional machine. An approach teachers often use to help students develop a useful mental model of a program is to hide the detail of how the program works and only gradually reveal its complexity. This approach is described with the metaphor of hiding the detail of elements of the program in a box. 

Data-driven models in machine learning systems are highly complex and make little sense to humans. Therefore, they may appear like magic boxes to students. This view needs to be banished. Machine learning is not magic. We have just not figured out yet how to explain the detail of data-driven models in a way that allows learners to form useful mental models.

An example of a representation of a machine learning model in TensorFlow, an online machine learning tool (Tedre & Vartiainen,2021).

Some existing ML tools aim to help learners form mental models of ML, for example through visual representations of how a neural network works (see Figure 2). But these explanations are still very complex. Clearly, we need to find new ways to help learners of all ages form useful mental models of machine learning, so that teachers can explain to them how machine learning systems work and banish the view that machine learning is magic.

Some tools and teaching approaches for ML education

Matti and Henriikka’s team piloted different tools and pedagogical approaches with different age groups of learners. In terms of tools, since large amounts of data are needed for machine learning projects, our presenters suggested that tools that enable lots of data to be easily collected are ideal for teaching activities. Media-rich education tools provide an opportunity to capture still images, movements, sounds, or sense other inputs and then use these as data in machine learning teaching activities. For example, to create a machine learning–based rock-paper-scissors game, students can take photographs of their hands to train a machine learning model using Google Teachable Machine.

Photos of hands are used to train a machine learning model as part of a project to create a rock-paper-scissors game.
Photos of hands are used to train a Teachable Machine machine learning model as part of a project to create a rock-paper-scissors game (Tedre & Vartiainen, 2021).

Similar to tools that teach classic programming to novice students (e.g. Scratch), some of the new classroom tools for teaching machine learning have a drag-and-drop interface (e.g. Cognimates). Using such tools means that in lessons, there can be less focus on one of the more complex aspects of learning to program, learning programming language syntax. However, not all machine learning education products include drag-and-drop interaction, some instead have their own complex languages (e.g. Wolfram Programming Lab), which are less attractive to teachers and learners. In their pilot studies, the Finnish team found that drag-and-drop machine learning tools appeared to work well with students of all ages.

The different pedagogical approaches the Finnish research team used in their pilot studies included an exploratory approach with preschool children, who investigated machine learning recognition of happy or sad faces; and a project-based approach with older students, who co-created machine learning apps with web-based tools such as Teachable Machine and Learn Machine Learning (built by the research team), supported by machine learning experts.

Example of a middle school (age 8 to 11) student’s pen and paper design for a machine learning app that recognises different instruments and chords.
Example of a middle school (age 8 to 11) student’s design for a machine learning app that recognises different instruments and chords (Tedre & Vartiainen, 2021).

What impact these pedagogies have on students’ long-term mental models about machine learning has yet to be researched. If you want to find out more about the classroom pilot studies, the academic paper is a very accessible read.

My take-aways: new opportunities, new research questions

We all learned a tremendous amount from Matti and Henriikka and their perspectives on this important topic. Our seminar participants asked them many questions about the pedagogies and practicalities of teaching machine learning in class, and raised concerns about squeezing more into an already packed computing curriculum.

For me, the most significant take-away from the seminar was the need to shift focus from algorithms to data and from CT 1.0 to CT 2.0. Learning how to best teach classical rule-driven programming has been a long journey that we have not yet completed. We are forming an understanding of what concepts learners need to be taught, the progression of learning, key mental models, pedagogical options, and assessment approaches. For teaching data-driven development, we need to do the same.  

The question of how we make sure teachers have the necessary understanding is key.

Jane Waite

I see the shift in problem solving approach as a chance to strengthen the teaching of computing in general, because it opens up opportunities to teach about systems, uncertainty, data, and society. I think it will help us raise awareness about design, context, creativity, and student agency. But I worry about how we will introduce this shift. In my view, there is a considerable risk that we will be sucked into open-ended, project-based learning, with busy and fun but shallow learning experiences that result in restricted conceptual development for students.

I also worry about how we can best help teachers build up the knowledge and experience to support their students. In the Q&A after the seminar, I asked Matti and Henriikka about the role of their team’s machine learning experts in their pilot studies. It seemed to me that without them, the pilot lessons would not have worked, as the participating teachers and students would not have had the vocabulary to talk about the process and would not have known what was doable given the available time, tools, and student knowledge.

The question of how we make sure teachers have the necessary understanding is key. Many existing professional development resources for teachers wanting to learn about ML seem to imply that teachers will all need a PhD in statistics and neural network optimisation to engage with machine learning education. This is misleading. But teachers do need to understand the machine learning concepts that their students need to learn about, and I think we don’t yet know exactly what these concepts are. 

In summary, clearly more research is needed. There are fundamental questions still to be answered about what, when, and how we teach data-driven approaches to software systems development and how this impacts what we teach about classical, rule-based programming. But to me, that is exciting, and I am very much looking forward to the journey ahead.

Join our next free seminar

To find out what others recommend about teaching AI and ML, catch up on last month’s seminar with Professor Carsten Schulte and colleagues on centring data instead of code in the teaching of AI.

We have another four seminars in our monthly series on AI, machine learning, and data science education. Find out more about them on this page, and catch up on past seminar blogs and recordings here.

At our next seminar on Tuesday 7 December at 17:00–18:30 GMT, we will welcome Professor Rose Luckin from University College London. She will be presenting on what it is about AI that makes it useful for teachers and learners.

We look forward to meeting you there!

PS You can build your understanding of machine learning by joining our latest free online course, where you’ll learn foundational concepts and train your own ML model!

The post The machine learning effect: Magic boxes and computational thinking 2.0 appeared first on Raspberry Pi.

Zabbix 6.0 LTS at Zabbix Summit Online 2021

Post Syndicated from Arturs Lontons original https://blog.zabbix.com/zabbix-6-0-lts-at-zabbix-summit-online-2021/16115/

With Zabbix Summit Online 2021 just around the corner, it’s time to have a quick overview of the 6.0 LTS features that we can expect to see featured during the event. The Zabbix 6.0 LTS release aims to deliver some of the long-awaited enterprise-level features while also improving the general user experience, performance, scalability, and many other aspects of Zabbix.

Native Zabbix server cluster

Many of you will be extremely happy to hear that Zabbix 6.0 LTS release comes with out-of-the-box High availability for Zabbix Server. This means that HA will now be supported natively, without having to use external tools to create Zabbix Server clusters.

The native Zabbix Server cluster will have a speech dedicated to it during the Zabbix Summit Online 2021. You can expect to learn both the inner workings of the HA solution, the configuration and of course the main benefits of using the native HA solution. You can also take a look at the in-development version of the native Zabbix server cluster in the latest Zabbix 6.0 LTS alpha release.

Business service monitoring and root cause analysis

Service monitoring is also about to go through a significant redesign, focusing on delivering additional value by providing robust Business service monitoring (BSM) features. This is achieved by delivering significant additions to the existing service status calculation logic. With features such as service weights, service status analysis based on child problem severities, ability to calculate service status based on the number or percentage of children in a problem state, users will be able to implement BSM on a whole new level. BSM will also support root cause analysis – users will be informed about the root cause problem of the service status change.

All of this and more, together with examples and use cases will be covered during a separate speech dedicated to BSM. In addition, some of the BSM features are available in the latest Zabbix 6.0 LTS alpha release – with more to come as we continue working on the Zabbix 6.0 release.

Audit log redesign

The Audit log is another existing feature that has received a complete redesign. With the ability to log each and every change performed both by the Zabbix Server and Zabbix Frontend, the Audit log will become an invaluable source of audit information. Of course, the redesign also takes performance into consideration – the redesign was developed with the least possible performance impact in mind.

The audit log is constantly in development and the current Zabbix 6.0 LTS alpha release offers you an early look at the feature. We will also be covering the technical details of the new audit log implementation during the Summit and will explain how we are able to achieve minimal performance impact with major improvements to Zabbix audit logging.

Geographical maps

With Geographical maps, our users can finally display their entities on a geographical map based on the coordinates of the entity. Geographical maps can be used with multiple geographical map providers and display your hosts with their most severe problems. In addition, geographical maps will react dynamically to Zoom levels and support filtering.

The latest Zabbix 6.0 Alpha release includes the Geomap widget – feel free to deploy it in your QA environment, check out the different map providers, filter options and other great features that come with this widget.

Machine learning

When it comes to problem detection, Zabbix 6.0 LTS will deliver multiple trend new functions. A specific set of functions provides machine learning functionality for Anomaly detection and Baseline monitoring.

The topic will be covered in-depth during the Zabbix Summit Online 2021. We will look at the configuration of the new functions and also take a deeper dive at the logic and algorithms used under the hood.

During the Zabbix Summit Online 2021, we will also cover many other new features, such as:

  • New Dashboard widgets
  • New items for Zabbix Agent
  • New templates and integrations
  • Zabbix login password complexity settings
  • Performance improvements for Zabbix Server, Zabbix Proxy, and Zabbix Frontend
  • UI and UX improvements
  • Zabbix login password complexity requirements
  • New history and trend functions
  • And more!

Not only will you get the chance to have an early look at many new features not yet available in the latest alpha release, but also you will have a great chance to learn the inner workings of the new features, the upgrade and migration process to Zabbix 6.0 LTS and much more!

We are extremely excited to share all of the new features with our community, so don’t miss out – take a look at the full Zabbix Summit online 2021 agenda and register for the event by visiting our Zabbix Summit page, and we will see you at the Zabbix Summit Online 2021 on November 25!

Batch Inference at Scale with Amazon SageMaker

Post Syndicated from Ramesh Jetty original https://aws.amazon.com/blogs/architecture/batch-inference-at-scale-with-amazon-sagemaker/

Running machine learning (ML) inference on large datasets is a challenge faced by many companies. There are several approaches and architecture patterns to help you tackle this problem. But no single solution may deliver the desired results for efficiency and cost effectiveness. In this blog post, we will outline a few factors that can help you arrive at the most optimal approach for your business. We will illustrate a use case and architecture pattern with Amazon SageMaker to perform batch inference at scale.

ML inference can be done in real time on individual records, such as with a REST API endpoint. Inference can also be done in batch mode as a processing job on a large dataset. While both approaches push data through a model, each has its own target goal when running inference at scale.

With real-time inference, the goal is usually to optimize the number of transactions per second that the model can process. With batch inference, the goal is usually tied to time constraints and the service-level agreement (SLA) for the job. Table 1 shows the key attributes of real-time, micro-batch, and batch inference scenarios.

Real Time Micro Batch Batch
Execution Mode
Synchronous Synchronous/Asynchronous Asynchronous
Prediction Latency
Subsecond Seconds to minutes Indefinite
Data Bounds Unbounded/stream Bounded Bounded
Execution Frequency
Variable Variable Variable/fixed
Invocation Mode
Continuous stream/API calls Event-based Event-based/scheduled
Examples Real-time REST API endpoint Data analyst running a SQL UDF Scheduled inference job

Table 1. Key characteristics of real-time, micro-batch, and batch inference scenarios

Key considerations for batch inference jobs

Batch inference tasks are usually good candidates for horizontal scaling. Each worker within a cluster can operate on a different subset of data without the need to exchange information with other workers. AWS offers multiple storage and compute options that enable horizontal scaling. Table 2 shows some key considerations when architecting for batch inference jobs.

  • Model type and ML framework. Models built with frameworks such as XGBoost and SKLearn require smaller compute instances. Those built with deep learning frameworks, such as TensorFlow and PyTorch require larger ones.
  • Complexity of the model. Simple models can run on CPU instances while more complex ensemble models and large-scale deep learning models can benefit from GPU instances.
  • Size of the inference data. While all approaches work on small datasets, larger datasets come with a unique set of challenges. The storage system must provide sufficient throughput and I/O to reliably run the inference workload.
  • Inference frequency and job concurrency. The volume of jobs within a fixed interval of time is an important consideration to address Service Quotas. The frequency and SLA requirements also proportionally impact the number of concurrent jobs. This might create additional pressure on the underlying Service Quotas.
ML Framework Model Complexity
Inference Data Size
Inference Frequency
Job Concurrency
  • Traditional
    • XGBoost
    • SKLearn
  • Deep Learning
    • Tensorflow
    • PyTorch
  • Low (linear models)
  • Medium (complex ensemble models)
  • High (large scale DL models)
  • Small (<1 GB)
  • Medium (<100 GB)
  • Large (<1 TB)
  • Hyperscale (>1 TB)
  • Hourly
  • Daily
  • Weekly
  • Monthly
  • 1
  • <10
  • <100
  • >100

Table 2. Key considerations when architecting for batch inference jobs

Real world Batch Inference use case and architecture

Often customers in certain domains such as advertising and marketing or healthcare must make predictions on hyperscale datasets. This requires deploying an inference pipeline that can complete several thousand inference jobs on extremely large datasets. The individual models used are typically of low complexity from a compute perspective. They could include a combination of various algorithms implemented in scikit-learn, XGBoost, and TensorFlow, for example. Most of the complexity in these use cases stems from large volumes of data and the number of concurrent jobs that must run to meet the service level agreement (SLA).

The batch inference architecture for these requirements typically is composed of three layers:

  • Orchestration layer. Manages the submission, scheduling, tracking, and error handling of individual jobs or multi-step pipelines
  • Storage layer. Stores the data that will be inferenced upon
  • Compute layer. Runs the inference job

There are several AWS services available that can be used for each of these architectural layers. The architecture in Figure 1 illustrates a real world implementation. Amazon SageMaker Processing and training services are used for compute layer and Amazon S3 for the storage layer. Amazon Managed Workflows for Apache Airflow (MWAA) and Amazon DynamoDB are used for the orchestration and job control layer.

Figure 1. Architecture for batch inference at scale with Amazon SageMaker

Figure 1. Architecture for batch inference at scale with Amazon SageMaker

Orchestration and job control layer. Apache Airflow is used to orchestrate the training and inference pipelines with job metadata captured into DynamoDB. At each step of the pipeline, Airflow updates the status of each model run. A custom Airflow sensor polls the status of each pipeline. It advances the pipeline with the successful completion of each step, or resubmits a job in case of failure.

Compute layer. SageMaker processing is used as the compute option for running the inference workload. SageMaker has a purpose-built batch transform feature for running batch inference jobs. However, this feature often requires additional pre and post-processing steps to get the data into the appropriate input and output format. SageMaker Processing offers a general purpose managed compute environment to run a custom batch inference container with a custom script. In the architecture, the processing script takes the input location of the model artifact generated by a SageMaker training job and the location of the inference data, and performs pre and post-processing along with model inference.

Storage layer. Amazon S3 is used to store the large input dataset and the output inference data. The ShardedByS3Key data distribution strategy distributes the files across multiple nodes within a processing cluster. With this option enabled, SageMaker Processing will automatically copy a different subset of input files into each node of the processing job. This way you can horizontally scale batch inference jobs by requesting a higher number of instances when configuring the job.

One caveat of this approach is that while many ML algorithms utilize multiple CPU cores during training, only one core is utilized during inference. This can be rectified by using Python’s native concurrency and parallelism frameworks such concurrent.futures. The following pseudo-code illustrates how you can distribute the inference workload across all instance cores. This assumes the SageMaker Processing job has been configured to copy the input files into the /opt/ml/processing/input directory.

from concurrent.futures import ProcessPoolExecutor, as_completed
from multiprocessing import cpu_count
import os
from glob import glob
import pandas as pd

def inference_fn(model_dir, file_path, output_dir):

model = joblib.load(f"{model_dir}/model.joblib")
data = pd.read_parquet(file_path)
data["prediction"] = model.predict(data)

output_path = f"{output_dir}/{os.path.basename(file_path)}"

data.to_parquet(output_path)

return output_path

input_files = glob("/opt/ml/processing/input/*")
model_dir = "/opt/ml/model"
output_dir = "/opt/ml/output"

with ProcessPoolExecutor(max_workers=cpu_count()) as executor:
futures = [executor.submit(inference_fn, model_dir, file_path, output_dir) for file in input_files]

results =[]
for future in as_completed(futures):
results.append(future.result())

Conclusion

In this blog post, we described ML inference options and use cases. We primarily focused on batch inference and reviewed key challenges faced when performing batch inference at scale. We provided a mental model of some key considerations and best practices to consider as you make various architecture decisions. We illustrated these considerations with a real world use case and an architecture pattern to perform batch inference at scale. This pattern can be extended to other choices of compute, storage, and orchestration services on AWS to build large-scale ML inference solutions.

More information:

Open-Sourcing a Monitoring GUI for Metaflow

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/open-sourcing-a-monitoring-gui-for-metaflow-75ff465f0d60

Open-Sourcing a Monitoring GUI for Metaflow, Netflix’s ML Platform

tl;dr Today, we are open-sourcing a long-awaited GUI for Metaflow. The Metaflow GUI allows data scientists to monitor their workflows in real-time, track experiments, and see detailed logs and results for every executed task. The GUI can be extended with plugins, allowing the community to build integrations to other systems, custom visualizations, and embed upcoming features of Metaflow directly into its views.

Metaflow is a full-stack framework for data science that we started developing at Netflix over four years ago and which we open-sourced in 2019. It allows data scientists to define ML workflows, test them locally, scale-out to the cloud, and deploy to production in idiomatic Python code. Since open-sourcing, the Metaflow community has been growing quickly: it is now the 7th most starred active project on Netflix’s GitHub account with nearly 4800 stars. Outside Netflix, Metaflow is used to power machine learning in production by hundreds of companies across industries from bioinformatics to real estate.

Since its inception, Metaflow has been a command-line-centric tool. It makes it easy for data scientists to express even complex machine learning applications in idiomatic Python, test them locally, or scale them out in the cloud — all using their favorite IDEs and terminals. Following our culture of freedom and responsibility, Metaflow grants data scientists the freedom to choose the right modeling approach, handle data and features flexibly, and construct workflows easily while ensuring that the resulting project executes responsibly and robustly on the production infrastructure.

As the number and criticality of projects running on Metaflow increased — some of which are very central to our business — our ML platform team started receiving an increasing number of support requests. Frequently, the questions were of the nature “can you help me understand why my flow takes so long to execute” or “how can I find the logs for a model that failed last night.” Technically, Metaflow provides a Python API that allows the user to inspect all details e.g., in a notebook, but writing code in a notebook to answer basic questions like this felt overkill and unnecessarily tedious. After observing the situation for months, we started forming an understanding of the kind of a new user interface that could address the growing needs of our users.

Requirements for a Metaflow GUI

Metaflow is a human-centered system by design. We consider our Python API and the CLI to be integral parts of the overall user interface and user experience, which singularly focuses on making it easier to build production-ready ML projects from scratch. In our approach, Python code provides a highly expressive and productive user interface for expressing complex business logic, such as ML models and workflows. At the same time, the CLI allows users to execute specific commands quickly and even automate common actions. When it comes to complex, real-life development work like this, it would be hard to achieve the same level of productivity on a graphical user interface.

However, textual UIs are quite lacking when it comes to discoverability and getting a holistic understanding of the system’s state. The questions we were hearing reflected this gap: we were lacking a user interface that would allow the users, quite simply, to figure out quickly what is happening in their Metaflow projects.

Netflix has a long history of developing innovative tools for observability, so when we began to specify requirements for the new GUI, we were able to leverage experiences from the previous GUIs built for other use cases, as well as real-life user stories from Metaflow users. We wanted to scope the GUI tightly, focusing on a specific gap in the Metaflow experience:

  1. The GUI should allow the users to see what flows and tasks are executing and what is happening inside them. Notably, we didn’t want to replace any of the functionality in the Metaflow APIs or CLI with the GUI — just to complement them. This meant that the GUI would be read-only: all actions like writing code and starting executions should happen on the users’ IDE and terminal as before. We also had no need to build a model-monitoring GUI yet, which is a wholly separate problem domain.
  2. The GUI would be targeted at professional data scientists. Instead of a fancy GUI for demos and presentations, we wanted a serious productivity tool with carefully thought-out user workflows that would fit seamlessly into our toolchain of data science. This requires attention to small details: for instance, users should be able to copy a link to any view in the GUI and share it e.g., on Slack, for easy collaboration and support (or to integrate with the Metaflow Slack bot). And, there should be natural affordances for navigating between the CLI, the GUI, and notebooks.
  3. The GUI should be scalable and snappy: it should handle our existing repository consisting of millions of runs, some of which contain tens of thousands of tasks without hiccups. Based on our experiences with other GUIs operating at Netflix-scale, this is not a trivial requirement: scalability needs to be baked into the design from the very beginning. Sluggish GUIs are hard to debug and fix afterwards, and they can have a significantly negative impact on productivity.
  4. The GUI should integrate well with other GUIs. A modern ML stack consists of many independent systems like data warehouses, compute layers, model serving systems, and, in particular, notebooks. It should be possible to find runs and tasks of interest in the Metaflow GUI and use a task-specific view to jump to other GUIs for further information. Our landscape of tools is constantly evolving, so we didn’t want to hardcode these links and views in the GUI itself. Instead, following the integration-friendly ethos of Metaflow, we want to embed relevant information in the GUI as plugins.
  5. Finally, we wanted to minimize the operational overhead of the GUI. In particular, under no circumstances should the GUI impact Metaflow executions. The GUI backend should be a simple service, optionally sitting alongside the existing Metaflow metadata service, providing a read-only, real-time view to the stored state. The frontend side should be easily extensible and maintainable, suggesting that we wanted a modern React app.

Monitoring GUI for Metaflow

As our ML Platform team had limited frontend resources, we reached out to Codemate to help with the implementation. As it often happens in software engineering projects, the project took longer than expected to finish, mostly because the problem of tracking and visualizing thousands of concurrent objects in real-time in a highly distributed environment is a surprisingly non-trivial problem (duh!). After countless iterations, we are finally very happy with the outcome, which we have now used in production for a few months.

When you open the GUI, you see an overview of all flows and runs, both current and historical, which you can group and filter in various ways:

Runs Grouped by flows

We can use this view for experiment tracking: Metaflow records every execution automatically, so data scientists can track all their work using this view. Naturally, the view can be grouped by user. They can also tag their runs and filter the view by tags, allowing them to focus on particular subsets of experiments.

After you click a specific run, you see all its tasks on a timeline:

Timeline view for a run

The timeline view is extremely useful in understanding performance bottlenecks, distribution of task runtimes, and finding failed tasks. At the top, you can see global attributes of the run, such as its status, start time, parameters etc. You can click a specific task to see more details:

Task view

This task view shows logs produced by a task, its results, and optionally links to other systems that are relevant to the task. For instance, if the task had deployed a model to a model serving platform, the view could include a link to a UI used for monitoring microservices.

As specified in our requirements, the GUI should work well with Metaflow CLI. To facilitate this, the top bar includes a navigation component where the user can copy-paste any pathspec, i.e., a path to any object in the Metaflow universe, which are prominently shown in the CLI output. This way, the user can easily move from the CLI to the GUI to observe runs and tasks in detail.

While the CLI is great, it is challenging to visualize flows. Each flow can be represented as a Directed Acyclic Graph (DAG), and so the GUI provides a much better way to visualize a flow. The DAG view presents all the steps of a flow and how they are related. Each step may have developer comments. They are colored to indicate the current state. Split steps are grouped by shaded boxes, while steps that participated in a foreach are grouped by a double shade box. Clicking on a step will take you to the Task view.

DAG View

Users at different organizations will likely have some special use cases that are not directly supported. The Metaflow GUI is extensible through its plugin API. For example, Netflix has its container orchestration platform called Titus. Users can configure tasks to utilize Titus to scale up or out. When failures happen, users will need to access their Titus containers for more information, and within the task view, a simple plugin provides a link for further troubleshooting.

Example task-level plugin

Try it at home!

We know that our user stories and requirements for a Metaflow GUI are not unique to Netflix. A number of companies in the Metaflow community have requested GUI for Metaflow in the past. To support the thriving community and invite 3rd party contributions to the GUI, we are open-sourcing our Monitoring GUI for Metaflow today!

You can find detailed instructions for how to deploy the GUI here. If you want to see the GUI in action before deploying it, Outerbounds, a new startup founded by our ex-colleagues, has deployed a public demo instance of the GUI. Outerbounds also hosts an active Slack community of Metaflow users where you can find support for GUI-related issues and share feedback and ideas for improvement.

With the new GUI, data scientists don’t have to fly blind anymore. Instead of reaching out to a platform team for support, they can easily see the state of their workflows on their own. We hope that Metaflow users outside Netflix will find the GUI equally beneficial, and companies will find creative ways to improve the GUI with new plugins.

For more context on the development process and motivation for the GUI, you can watch this recording of the GUI launch meetup.


Open-Sourcing a Monitoring GUI for Metaflow was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Using Machine Learning to Guess PINs from Video

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/10/using-machine-learning-to-guess-pins-from-video.html

Researchers trained a machine-learning system on videos of people typing their PINs into ATMs:

By using three tries, which is typically the maximum allowed number of attempts before the card is withheld, the researchers reconstructed the correct sequence for 5-digit PINs 30% of the time, and reached 41% for 4-digit PINs.

This works even if the person is covering the pad with their hands.

The article doesn’t contain a link to the original research. If someone knows it, please put it in the comments.

Slashdot thread.

Learn the fundamentals of AI and machine learning with our free online course

Post Syndicated from Michael Conterio original https://www.raspberrypi.org/blog/fundamentals-ai-machine-learning-free-online-course/

Join our free online course Introduction to Machine Learning and AI to discover the fundamentals of machine learning and learn to train your own machine learning models using free online tools.

Drawing of a machine learning robot helping a human identify spam at a computer.

Although artificial intelligence (AI) was once the province of science fiction, these days you’re very likely to hear the term in relation to new technologies, whether that’s facial recognition, medical diagnostic tools, or self-driving cars, which use AI systems to make decisions or predictions.

By the end of this free online course, you will have an appreciation for what goes into machine learning and artificial intelligence systems — and why you should think carefully about what comes out.

Machine learning — a brief overview

You’ll also often hear about AI systems that use machine learning (ML). Very simply, we can say that programs created using ML are ‘trained’ on large collections of data to ‘learn’ to produce more accurate outputs over time. One rather funny application you might have heard of is the ‘muffin or chihuahua?’ image recognition task.

Drawing of a machine learning ars rover trying to decide whether it is seeing an alien or a rock.

More precisely, we would say that a ML algorithm builds a model, based on large collections of data (the training data), without being explicitly programmed to do so. The model is ‘finished’ when it makes predictions or decisions with an acceptable level of accuracy. (For example, it rarely mistakes a muffin for a chihuahua in a photo.) It is then considered to be able to make predictions or decisions using new data in the real world.

It’s important to understand AI and ML — especially for educators

But how does all this actually work? If you don’t know, it’s hard to judge what the impacts of these technologies might be, and how we can be sure they benefit everyone — an important discussion that needs to involve people from across all of society. Not knowing can also be a barrier to using AI, whether that’s for a hobby, as part of your job, or to help your community solve a problem.

some things that machine learning and AI systems can be built into: streetlamps, waste collecting vehicles, cars, traffic lights.

For teachers and educators it’s particularly important to have a good foundational knowledge of AI and ML, as they need to teach their learners what the young people need to know about these technologies and how they impact their lives. (We’ve also got a free seminar series about teaching these topics.)

To help you understand the fundamentals of AI and ML, we’ve put together a free online course: Introduction to Machine Learning and AI. Over four weeks in two hours per week, you’ll learn how machine learning can be used to solve problems, without going too deeply into the mathematical details. You’ll also get to grips with the different ways that machines ‘learn’, and you will try out online tools such as Machine Learning for Kids and Teachable Machine to design and train your own machine learning programs.

What types of problems and tasks are AI systems used for?

As well as finding out how these AI systems work, you’ll look at the different types of tasks that they can help us address. One of these is classification — working out which group (or groups) something fits in, such as distinguishing between positive and negative product reviews, identifying an animal (or a muffin) in an image, or spotting potential medical problems in patient data.

You’ll also learn about other types of tasks ML programs are used for, such as regression (predicting a numerical value from a continuous range) and knowledge organisation (spotting links between different pieces of data or clusters of similar data). Towards the end of the course you’ll dive into one of the hottest topics in AI today: neural networks, which are ML models whose design is inspired by networks of brain cells (neurons).

drawing of a small machine learning neural network.

Before an ML program can be trained, you need to collect data to train it with. During the course you’ll see how tools from statistics and data science are important for ML — but also how ethical issues can arise both when data is collected and when the outputs of an ML program are used.

By the end of the course, you will have an appreciation for what goes into machine learning and artificial intelligence systems — and why you should think carefully about what comes out.

Sign up to the course today, for free

The Introduction to Machine Learning and AI course is open for you to sign up to now. Sign-ups will pause after 12 December. Once you sign up, you’ll have access for six weeks. During this time you’ll be able to interact with your fellow learners, and before 25 October, you’ll also benefit from the support of our expert facilitators. So what are you waiting for?

Share your views as part of our research

As part of our research on computing education, we would like to find out about educators’ views on machine learning. Before you start the course, we will ask you to complete a short survey. As a thank you for helping us with our research, you will be offered the chance to take part in a prize draw for a £50 book token!

Learn more about AI, its impacts, and teaching learners about them

To develop your computing knowledge and skills, you might also want to:

If you are a teacher in England, you can develop your teaching skills through the National Centre for Computing Education, which will give you free upgrades for our courses (including Introduction to Machine Learning and AI) so you’ll receive certificates and unlimited access.

The post Learn the fundamentals of AI and machine learning with our free online course appeared first on Raspberry Pi.

Should we teach AI and ML differently to other areas of computer science? A challenge

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/research-seminar-data-centric-ai-ml-teaching-in-school/

Between September 2021 and March 2022, we’re partnering with The Alan Turing Institute to host a series of free research seminars about how to teach AI and data science to young people.

In the second seminar of the series, we were excited to hear from Professor Carsten Schulte, Yannik Fleischer, and Lukas Höper from the University of Paderborn, Germany, who presented on the topic of teaching AI and machine learning (ML) from a data-centric perspective. Their talk raised the question of whether and how AI and ML should be taught differently from other themes in the computer science curriculum at school.

Machine behaviour — a new field of study?

The rationale behind the speakers’ work is a concept they call hybrid interaction system, referring to the way that humans and machines interact. To explain this concept, Carsten referred to an 2019 article published in Nature by Iyad Rahwan and colleagues: Machine hehaviour. The article’s authors propose that the study of AI agents (complex and simple algorithms that make decisions) should be a separate, cross-disciplinary field of study, because of the ubiquity and complexity of AI systems, and because these systems can have both beneficial and detrimental impacts on humanity, which can be difficult to evaluate. (Our previous seminar by Mhairi Aitken highlighted some of these impacts.) The authors state that to study this field, we need to draw on scientific practices from across different fields, as shown below:

Machine behaviour as a field sits at the intersection of AI engineering and behavioural science. Quantitative evidence from machine behaviour studies feeds into the study of the impact of technology, which in turn feeds questions and practices into engineering and behavioural science.
The interdisciplinarity of machine behaviour. (Image taken from Rahwan et al [1])

In establishing their argument, the authors compare the study of animal behaviour and machine behaviour, citing that both fields consider aspects such as mechanism, development, evolution and function. They describe how part of this proposed machine behaviour field may focus on studying individual machines’ behaviour, while collective machines and what they call ‘hybrid human-machine behaviour’ can also be studied. By focusing on the complexities of the interactions between machines and humans, we can think both about machines shaping human behaviour and humans shaping machine behaviour, and a sort of ‘co-behaviour’ as they work together. Thus, the authors conclude that machine behaviour is an interdisciplinary area that we should study in a different way to computer science.

Carsten and his team said that, as educators, we will need to draw on the parameters and frameworks of this machine behaviour field to be able to effectively teach AI and machine learning in school. They argue that our approach should be centred on data, rather than on code. I believe this is a challenge to those of us developing tools and resources to support young people, and that we should be open to these ideas as we forge ahead in our work in this area.

Ideas or artefacts?

In the interpretation of computational thinking popularised in 2006 by Jeanette Wing, she introduces computational thinking as being about ‘ideas, not artefacts’. When we, the computing education community, started to think about computational thinking, we moved from focusing on specific technology — and how to understand and use it — to the ideas or principles underlying the domain. The challenge now is: have we gone too far in that direction?

Carsten argued that, if we are to understand machine behaviour, and in particular, human-machine co-behaviour, which he refers to as the hybrid interaction system, then we need to be studying   artefacts as well as ideas.

Throughout the seminar, the speakers reminded us to keep in mind artefacts, issues of bias, the role of data, and potential implications for the way we teach.

Studying machine learning: a different focus

In addition, Carsten highlighted a number of differences between learning ML and learning other areas of computer science, including traditional programming:

  1. The process of problem-solving is different. Traditionally, we might try to understand the problem, derive a solution in terms of an algorithm, then understand the solution. In ML, the data shapes the model, and we do not need a deep understanding of either the problem or the solution.
  2. Our tolerance of inaccuracy is different. Traditionally, we teach young people to design programs that lead to an accurate solution. However, the nature of ML means that there will be an error rate, which we strive to minimise. 
  3. The role of code is different. Rather than the code doing the work as in traditional programming, the code is only a small part of a real-world ML system. 

These differences imply that our teaching should adapt too.

A graphic demonstrating that in machine learning as compared to other areas of computer science, the process of problem-solving, tolerance of inaccuracy, and role of code is different.
Click to enlarge.

ProDaBi: a programme for teaching AI, data science, and ML in secondary school

In Germany, education is devolved to state governments. Although computer science (known as informatics) was only last year introduced as a mandatory subject in lower secondary schools in North Rhine-Westphalia, where Paderborn is located, it has been taught at the upper secondary levels for many years. ProDaBi is a project that researchers have been running at Paderborn University since 2017, with the aim of developing a secondary school curriculum around data science, AI, and ML.

The ProDaBi curriculum includes:

  • Two modules for 11- to 12-year-olds covering decision trees and data awareness (ethical aspects), introduced this year
  • A short course for 13-year-olds covering aspects of artificial intelligence, through the game Hexapawn
  • A set of modules for 14- to 15-year-olds, covering data science, data exploration, decision trees, neural networks, and data awareness (ethical aspects), using Jupyter notebooks
  • A project-based course for 18-year-olds, including the above topics at a more advanced level, using Codap and Jupyter notebooks to develop practical skills through projects; this course has been running the longest and is currently in its fourth iteration

Although the ProDaBi project site is in German, an English translation is available.

Learning modules developed as part of the ProDaBi project.
Modules developed as part of the ProDaBi project

Our speakers described example activities from three of the modules:

  • Hexapawn, a two-player game inspired by the work of Donald Michie in 1961. The purpose of this activity is to support learners in reflecting on the way the machine learns. Children can then relate the activity to the behavior of AI agents such as autonomous cars. An English version of the activity is available. 
  • Data cards, a series of activities to teach about decision trees. The cards are designed in a ‘Top Trumps’ style, and based on food items, with unplugged and digital elements. 
  • Data awareness, a module focusing on the amount of data an individual can generate as they move through a city, in this case through the mobile phone network. Children are encouraged to reflect on personal data in the context of the interaction between the human and data-driven artefact, and how their view of the world influences their interpretation of the data that they are given.

Questioning how we should teach AI and ML at school

There was a lot to digest in this seminar: challenging ideas and some new concepts, for me anyway. An important takeaway for me was how much we do not yet know about the concepts and skills we should be teaching in school around AI and ML, and about the approaches that we should be using to teach them effectively. Research such as that being carried out in Paderborn, demonstrating a data-centric approach, can really augment our understanding, and I’m looking forward to following the work of Carsten and his team.

Carsten and colleagues ended with this summary and discussion point for the audience:

“‘AI education’ requires developing an adequate picture of the hybrid interaction system — a kind of data-driven, emergent ecosystem which needs to be made explicitly to understand the transformative role as well as the technological basics of these artificial intelligence tools and how they are related to data science.”

You can catch up on the seminar, including the Q&A with Carsten and his colleagues, here:

Join our next seminar

This seminar really extended our thinking about AI education, and we look forward to introducing new perspectives from different researchers each month. At our next seminar on Tuesday 2 November at 17:00–18:30 BST / 12:00–13:30 EDT / 9:00–10:30 PDT / 18:00–19:30 CEST, we will welcome Professor Matti Tedre and Henriikka Vartiainen (University of Eastern Finland). The two Finnish researchers will talk about emerging trajectories in ML education for K-12. We look forward to meeting you there.

Carsten and their colleagues are also running a series of seminars on AI and data science: you can find out about these on their registration page.

You can increase your own understanding of machine learning by joining our latest free online course!


[1] Rahwan, I., Cebrian, M., Obradovich, N., Bongard, J., Bonnefon, J. F., Breazeal, C., … & Wellman, M. (2019). Machine behaviour. Nature, 568(7753), 477-486.

The post Should we teach AI and ML differently to other areas of computer science? A challenge appeared first on Raspberry Pi.

Machine Learning Prosthetic Arm | The MagPi #110

Post Syndicated from Phil King original https://www.raspberrypi.org/blog/machine-learning-prosthetic-arm-the-magpi-110/

This intelligent arm learns how to move naturally, based on what the wearer is doing, as Phil King discovers in the latest issue of The MagPi, out now.

Known for his robotic creations, popular YouTuber James Bruton is also a keen Iron Man cosplayer, and his latest invention would surely impress Tony Stark: an intelligent prosthetic arm that can move naturally and autonomously, depending on the wearer’s body posture and limb movements.

Equipped with three heavy-duty servos, the prosthetic arm moves naturally based on the data from IMU sensors on the wearer’s other limbs

“It’s a project I’ve been thinking about for a while, but I’ve never actually attempted properly,” James tells us. “I thought it would be good to have a work stream of something that could be useful.”

Motion capture suit

To obtain the body movement data on which to base the arm’s movements, James considered using a brain computer, but this would be unreliable without embedding electrodes in his head! So, he instead opted to train it with machine learning.

For this he created a motion capture suit from 3D-printed parts to gather all the data from his body motions: arms, legs, and head. The suit measures joint movements using rotating pieces with magnetic encoders, along with limb and head positions – via a special headband – using MPU-6050 inertial measurement units and Teensy LC boards.

Part of the motion capture suit, the headband is equipped with an IMU to gather movement data

Collected by a Teensy 4.1, this data is then fed into a machine learning model running on the suit’s Raspberry Pi Zero using AOgmaNeo, a lightweight C++ software library designed to run on low-power devices such a microcontrollers.

“AOgmaNeo is a reinforcement machine learning system which learns what all of the data is doing in relation to itself,” James explains. “This means that you can remove any piece of data and, after training, the software will do its best to replace the missing piece with a learned output. In my case, I’m removing the right arm and using the learned output to drive the prosthetic arm, but it could be any limb.”

While James notes that AOgmaNeo is actually meant for reinforcement learning,“in this case we know what the output should be rather than it being unknown and learning through binary reinforcement.”

The motion capture suit comprises 3D-printed parts, each equipped with a magnetic rotary encoder, MPU-6050 IMU, and Teensy LC

To train the model, James used distinctive repeated motions, such as walking, so that the prosthetic arm would later be able to predict what it should do from incoming sensor data. He also spent some time standing still so that the arm would know what to do in that situation.

New model arm

With the machine learning model trained, Raspberry Pi Zero can be put into playback mode to control the backpack-mounted arm’s movements intelligently. It can then duplicate what the wearer’s real right arm was doing during training depending on the positions and movements of other body parts.

So, as he demonstrates in his YouTube video, if James starts walking on the spot, the prosthetic arm swings the opposite way to his left arm as he strides along, and moves forward as raises his left leg. If he stands still, the arm will hang down by his side. The 3D-printed hand was added purely for aesthetic reasons and the fingers don’t move.

Subscribe to James’ YouTube channel

James admits that the project is highly experimental and currently an early work in progress. “I’d like to develop this concept further,” he says, “although the current setup is slightly overambitious and impractical. I think the next step will be to have a simpler set of inputs and outputs.”

While he generally publishes his CAD designs and code, the arm “doesn’t work all that well, so I haven’t this time. AOgmaNeo is open-source, though (free for personal use), so you can make something similar if you wished.” What would you do with an extra arm? 

Get The MagPi #110 NOW!

MagPi 110 Halloween cover

You can grab the brand-new issue right now from the Raspberry Pi Press store, or via our app on Android or iOS. You can also pick it up from supermarkets and newsagents. There’s also a free PDF you can download.

The post Machine Learning Prosthetic Arm | The MagPi #110 appeared first on Raspberry Pi.

What’s a kangaroo?! AI ethics lessons for and from the younger generation

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/ai-ethics-lessons-education-children-research/

Between September 2021 and March 2022, we’re partnering with The Alan Turing Institute to host speakers from the UK, Finland, Germany, and the USA presenting a series of free research seminars about AI and data science education for young people. These rapidly developing technologies have a huge and growing impact on our lives, so it’s important for young people to understand them both from a technical and a societal perspective, and for educators to learn how to best support them to gain this understanding.

Mhairi Aitken.

In our first seminar we were beyond delighted to hear from Dr Mhairi Aitken, Ethics Fellow at The Alan Turing Institute. Mhairi is a sociologist whose research examines social and ethical dimensions of digital innovation, particularly relating to uses of data and AI. You can catch up on her full presentation and the Q&A with her in the video below.

Why we need AI ethics

The increased use of AI in society and industry is bringing some amazing benefits. In healthcare for example, AI can facilitate early diagnosis of life-threatening conditions and provide more accurate surgery through robotics. AI technology is also already being used in housing, financial services, social services, retail, and marketing. Concerns have been raised about the ethical implications of some aspects of these technologies, and Mhairi gave examples of a number of controversies to introduce us to the topic.

“Ethics considers not what we can do but rather what we should do — and what we should not do.”

Mhairi Aitken

One such controversy in England took place during the coronavirus pandemic, when an AI system was used to make decisions about school grades awarded to students. The system’s algorithm drew on grades awarded in previous years to other students of a school to upgrade or downgrade grades given by teachers; this was seen as deeply unfair and raised public consciousness of the real-life impact that AI decision-making systems can have.
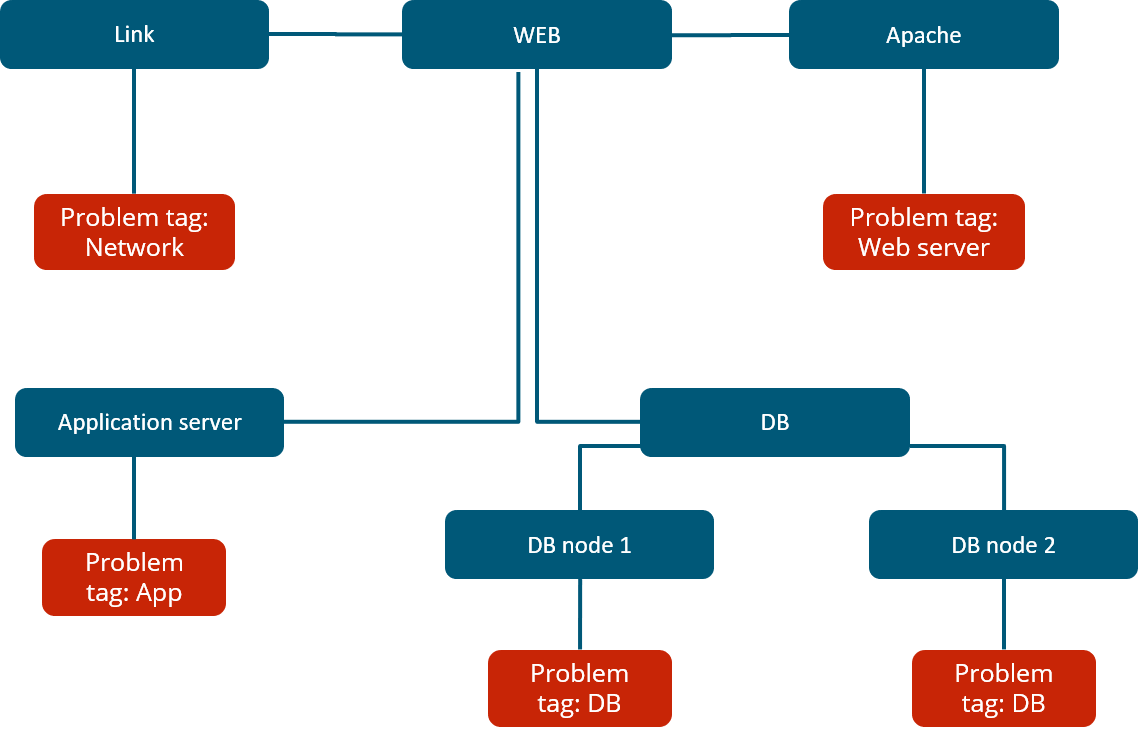
An AI system was used in England last year to make decisions about school grades awarded to students — this was seen as deeply unfair.

Another high-profile controversy was caused by biased machine learning-based facial recognition systems and explored in Shalini Kantayya’s documentary Coded Bias. Such facial recognition systems have been shown to be much better at recognising a white male face than a black female one, demonstrating the inequitable impact of the technology.

What should AI be used for?

There is a clear need to consider both the positive and negative impacts of AI in society. Mhairi stressed that using AI effectively and ethically is not just about mitigating negative impacts but also about maximising benefits. She told us that bringing ethics into the discussion means that we start to move on from what AI applications can do to what they should and should not do. To outline how ethics can be applied to AI, Mhairi first outlined four key ethical principles:

  • Beneficence (do good)
  • Nonmaleficence (do no harm)
  • Autonomy
  • Justice

Mhairi shared a number of concrete questions that ethics raise about new technologies including AI: 

  • How do we ensure the benefits of new technologies are experienced equitably across society?
  • Do AI systems lead to discriminatory practices and outcomes?
  • Do new forms of data collection and monitoring threaten individuals’ privacy?
  • Do new forms of monitoring lead to a Big Brother society?
  • To what extent are individuals in control of the ways they interact with AI technologies or how these technologies impact their lives?
  • How can we protect against unjust outcomes, ensuring AI technologies do not exacerbate existing inequalities or reinforce prejudices?
  • How do we ensure diverse perspectives and interests are reflected in the design, development, and deployment of AI systems? 

Who gets to inform AI systems? The kangaroo metaphor

To mitigate negative impacts and maximise benefits of an AI system in practice, it’s crucial to consider the context in which the system is developed and used. Mhairi illustrated this point using the story of an autonomous vehicle, a self-driving car, developed in Sweden in 2017. It had been thoroughly safety-tested in the country, including tests of its ability to recognise wild animals that may cross its path, for example elk and moose. However, when the car was used in Australia, it was not able to recognise kangaroos that hopped into the road! Because the system had not been tested with kangaroos during its development, it did not know what they were. As a result, the self-driving car’s safety and reliability significantly decreased when it was taken out of the context in which it had been developed, jeopardising people and kangaroos.
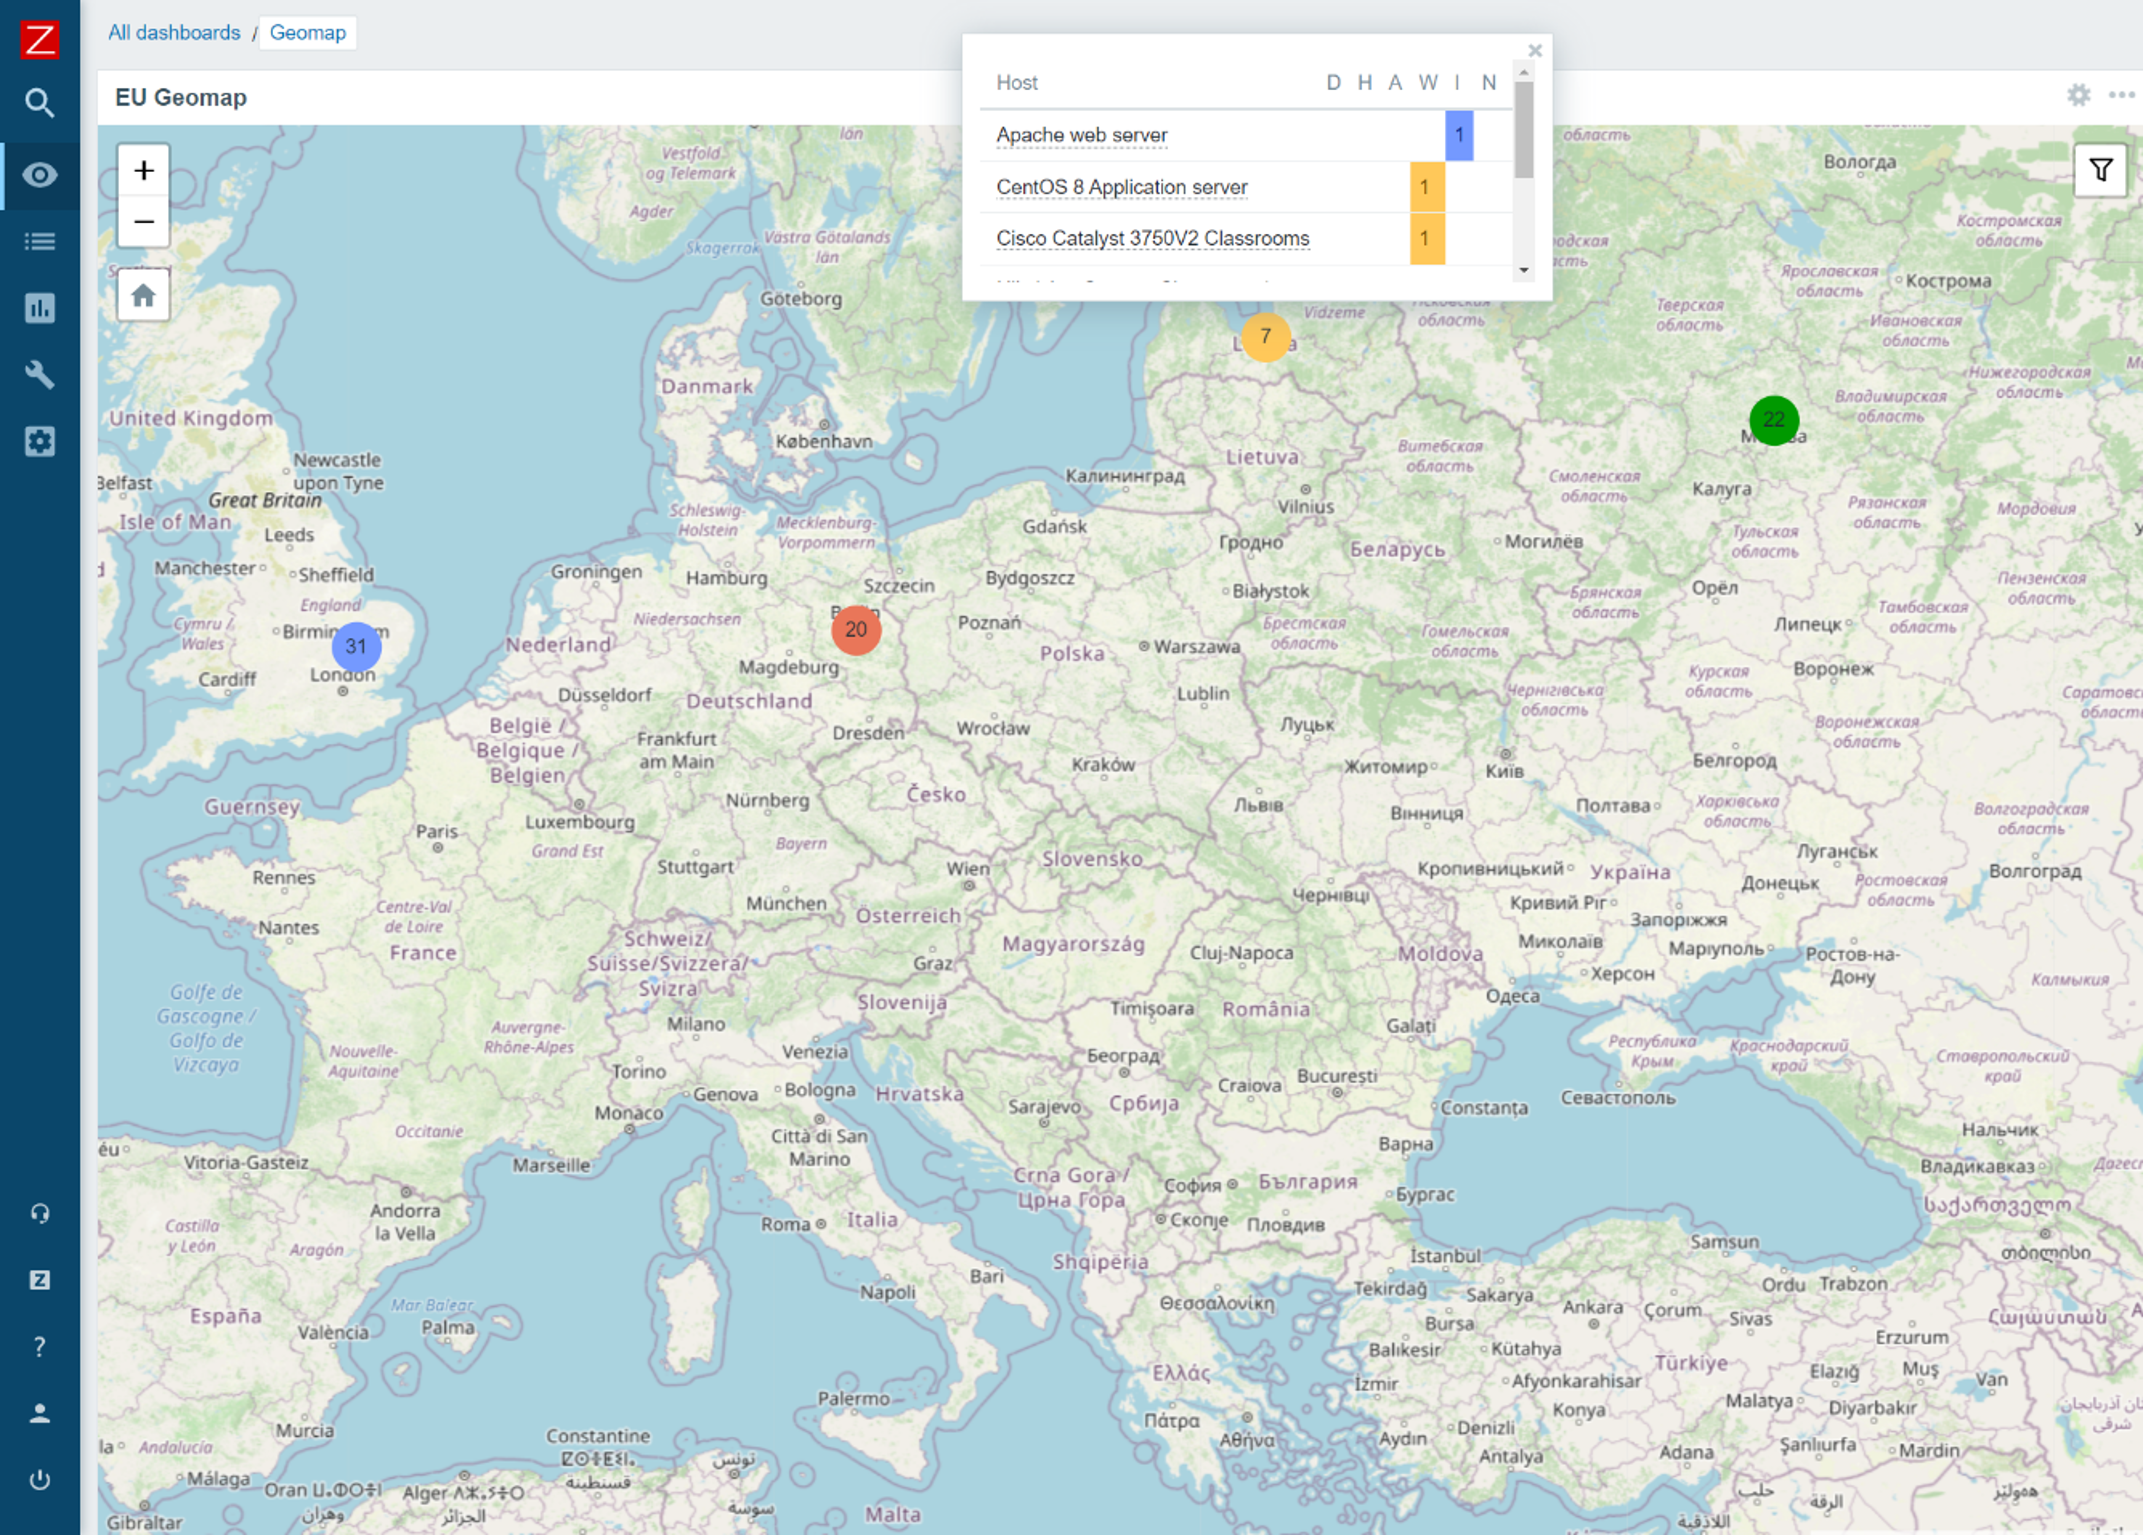
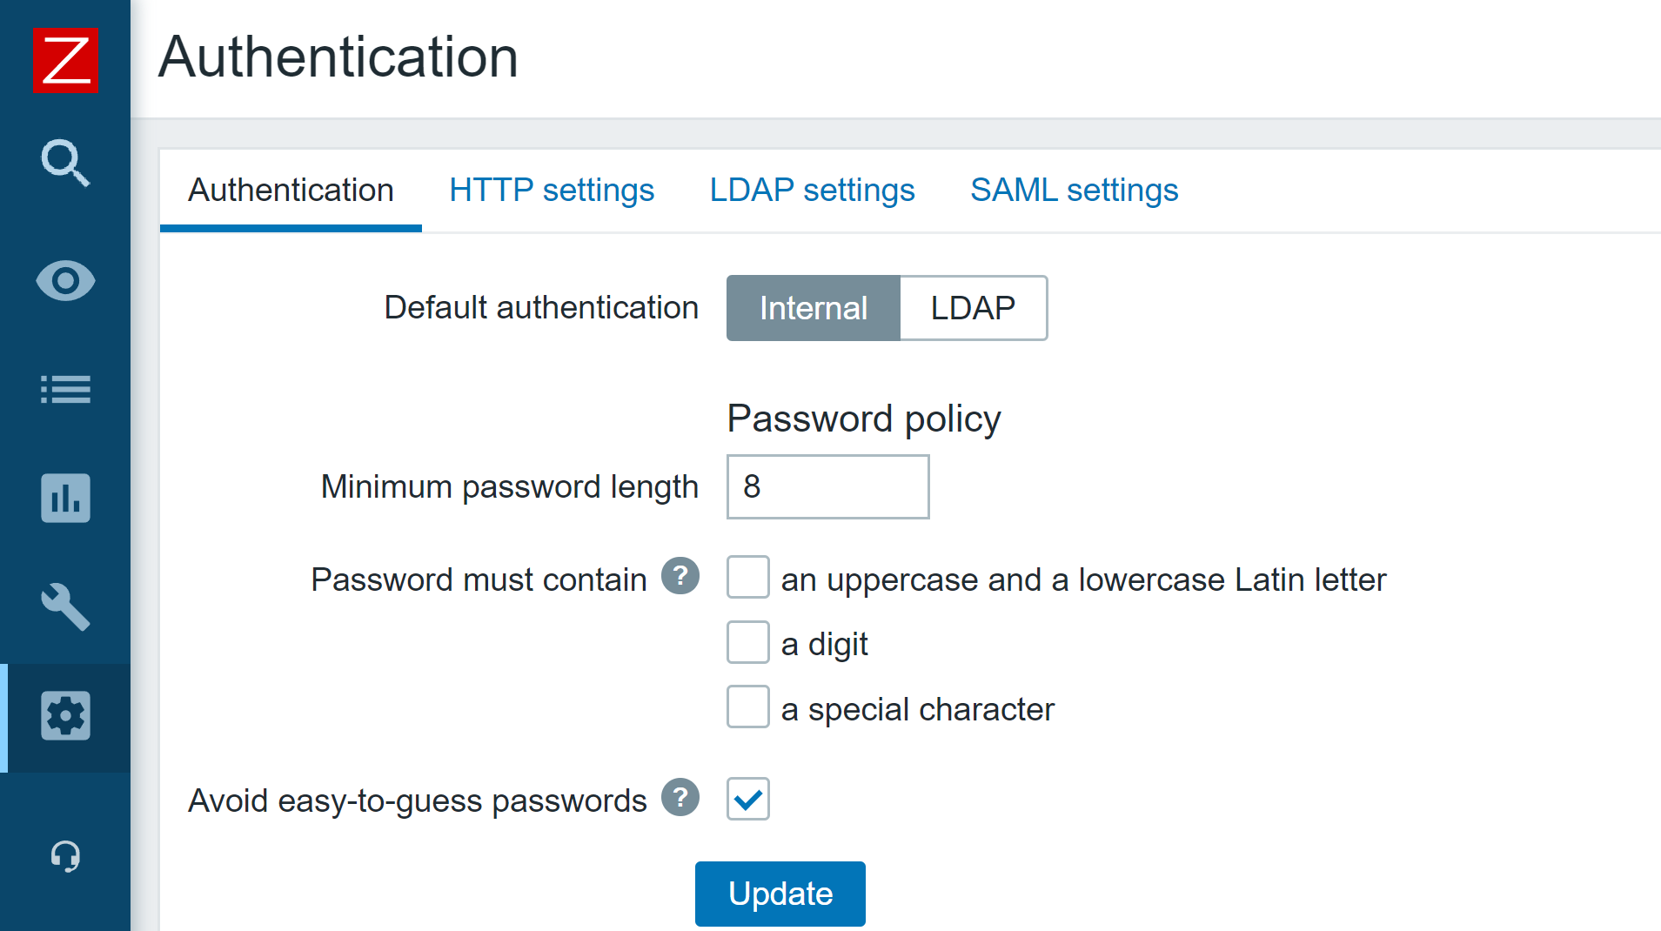
A parent kangaroo with a young kangaroo in its pouch stands on grass.
Mitigating negative impacts and maximising benefits of AI systems requires actively involving the perspectives of groups that may be affected by the system — ‘kangoroos’ in Mhairi’s metaphor.

Mhairi used the kangaroo example as a metaphor to illustrate ethical issues around AI: the creators of an AI system make certain assumptions about what an AI system needs to know and how it needs to operate; these assumptions always reflect the positions, perspectives, and biases of the people and organisations that develop and train the system. Therefore, AI creators need to include metaphorical ‘kangaroos’ in the design and development of an AI system to ensure that their perspectives inform the system. Mhairi highlighted children as an important group of ‘kangaroos’. 

AI in children’s lives

AI may have far-reaching consequences in children’s lives, where it’s being used for decision-making around access to resources and support. Mhairi explained the impact that AI systems are already having on young people’s lives through these systems’ deployment in children’s education, in apps that children use, and in children’s lives as consumers.

A young child sits at a table using a tablet.
AI systems are already having an impact on children’s lives.

Children can be taught not only that AI impacts their lives, but also that it can get things wrong and that it reflects human interests and biases. However, Mhairi was keen to emphasise that we need to find out what children know and want to know before we make assumptions about what they should be taught. Moreover, engaging children in discussions about AI is not only about them learning about AI, it’s also about ethical practice: what can people making decisions about AI learn from children by listening to their views and perspectives?

AI research that listens to children

UNICEF, the United Nations Children’s Fund, has expressed concerns about the impact of new AI technologies used on children and young people. They have developed the UNICEF Requirements for Child-Centred AI.
Unicef Requirements for Child-Centred AI: Support childrenʼs development and well-being. Ensure inclusion of and for children. Prioritise fairness and non-discrimination for children. Protect childrenʼs data and privacy. Ensure safety for children. Provide transparency, explainability, and accountability for children. Empower governments and businesses with knowledge of AI and childrenʼs rights. Prepare children for present and future developments in AI. Create an enabling environment for child-centred AI. Engage in digital cooperation.
UNICEF’s requirements for child-centred AI, as presented by Mhairi. Click to enlarge.

Together with UNICEF, Mhairi and her colleagues working on the Ethics Theme in the Public Policy Programme at The Alan Turing Institute are engaged in new research to pilot UNICEF’s Child-Centred Requirements for AI, and to examine how these impact public sector uses of AI. A key aspect of this research is to hear from children themselves and to develop approaches to engage children to inform future ethical practices relating to AI in the public sector. The researchers hope to find out how we can best engage children and ensure that their voices are at the heart of the discussion about AI and ethics.

We all learned a tremendous amount from Mhairi and her work on this important topic. After her presentation, we had a lively discussion where many of the participants relayed the conversations they had had about AI ethics and shared their own concerns and experiences and many links to resources. The Q&A with Mhairi is included in the video recording.

What we love about our research seminars is that everyone attending can share their thoughts, and as a result we learn so much from attendees as well as from our speakers!

It’s impossible to cover more than a tiny fraction of the seminar here, so I do urge you to take the time to watch the seminar recording. You can also catch up on our previous seminars through our blogs and videos.

Join our next seminar

We have six more seminars in our free series on AI, machine learning, and data science education, taking place every first Tuesday of the month. At our next seminar on Tuesday 5 October at 17:00–18:30 BST / 12:00–13:30 EDT / 9:00–10:30 PDT / 18:00–19:30 CEST, we will welcome Professor Carsten Schulte, Yannik Fleischer, and Lukas Höper from the University of Paderborn, Germany, who will be presenting on the topic of teaching AI and machine learning (ML) from a data-centric perspective (find out more here). Their talk will raise the questions of whether and how AI and ML should be taught differently from other themes in the computer science curriculum at school.

Sign up now and we’ll send you the link to join on the day of the seminar — don’t forget to put the date in your diary.

I look forward to meeting you there!

In the meantime, we’re offering a brand-new, free online course that introduces machine learning with a practical focus — ideal for educators and anyone interested in exploring AI technology for the first time.

The post What’s a kangaroo?! AI ethics lessons for and from the younger generation appeared first on Raspberry Pi.