Can you believe it? We’re nearly at the end of 2025. And what a year it’s been! From re:Invent recap events, to AWS Summits, AWS Innovate, AWS re:Inforce, Community Days, and DevDays and, recently, adding that cherry on the cake, re:Invent 2025, we have lived through a year filled with exciting moments and technology advancements which continue to shape our new modern world.
Speaking of re:Invent, if you haven’t caught up yet on all the new releases and announcements (and there were plenty of exciting launches across every area), be sure to check out our curated post highlighting the top announcements from AWS re:Invent 2025. We’ve organized all the key releases into easy-to-navigate categories and included links so you can dive deeper into anything that sparks your interest.
While the year may be wrapping up, our teams are still busy working on things that you have either asked for as customers or that we pro-actively create to make your lives easier. Last week had quite a few interesting releases as usual, so let’s look at a few that I think could be useful for many of you out there.
Last week’s launches
Amazon WorkSpaces Secure Browser introduces Web Content Filtering – Organizations can now control web access through category-based filtering across 25+ predefined categories, granular URL policies, and integrated compliance logging. The feature works alongside existing Chrome policies and integrates with Session Logger for enhanced monitoring and is available at no additional cost in 10 AWS Regions with pay-as-you-go pricing.
Amazon Aurora DSQL now supports cluster creation in seconds – Developers can now instantly provision Aurora DSQL databases with setup time reduced from minutes to seconds, enabling rapid prototyping through the integrated AWS console query editor or AI-powered development via the Aurora DSQL Model Context Protocol server. Available at no additional cost in all AWS Regions where Aurora DSQL is offered, with AWS Free Tier access available.
Amazon Aurora PostgreSQL now supports integration with Kiro powers – Developers can now accelerate Aurora PostgreSQL application development using AI-assisted coding through Kiro powers, a repository of pre-packaged Model Context Protocol servers. The Aurora PostgreSQL integration provides direct database connectivity for queries, schema management, and cluster operations, dynamically loading relevant context as developers work. Available for one-click installation in Kiro IDE across all AWS Regions.
Amazon ECS now supports custom container stop signals on AWS Fargate – Fargate tasks now honor the stop signal configured in container images, enabling graceful shutdowns for containers that rely on signals like SIGQUIT or SIGINT instead of the default SIGTERM. The ECS container agent reads the STOPSIGNAL instruction from OCI-compliant images and sends the appropriate signal during task termination. Available at no additional cost across all AWS Regions.
Amazon CloudWatch SDK supports optimized JSON, CBOR protocols – CloudWatch SDK now defaults to JSON and CBOR protocols, delivering lower latency, reduced payload sizes, and decreased client-side CPU and memory usage compared to the traditional AWS Query protocol. Available at no additional cost across all AWS Regions and SDK language variants.
Amazon Cognito identity pools now support private connectivity with AWS PrivateLink – Organizations can now securely exchange federated identities for temporary AWS credentials through private VPC connections, eliminating the need to route authentication traffic over the public internet. Available in all AWS Regions where Cognito identity pools are supported, except AWS China (Beijing) and AWS GovCloud (US) Regions.
AWS Application Migration Service supports IPv6 – Organizations can now migrate applications using IPv6 addressing through dual-stack service endpoints that support both IPv4 and IPv6 communications. During replication, testing, and cutover phases, you can use IPv4, IPv6, or dual-stack configurations to launch servers in your target environment. Available at no additional cost in all AWS Regions that support MGN and EC2 dual-stack endpoints.
And that’s it for the AWS News Blog Weekly Roundup…not just for this week, but for 2025! We’ll be taking a break and returning in January to continue bringing you the latest AWS releases and updates.
As we close out 2025, it’s remarkable to look back at just how much has changed since the beginning of year. From groundbreaking AI capabilities to transformative infrastructure innovations, AWS has delivered an incredible year of releases that have reshaped what’s possible in the cloud. Throughout it all, the AWS News Blog has been right here with you every week with our Weekly Roundup series, helping you stay informed and ready to take advantage of each new opportunity as it arrived. We’re grateful you’ve joined us on this journey, and we can’t wait to continue bringing you the latest AWS innovations when we return in January 2026.
Until then, happy building, and here’s to an even more exciting year ahead!
Cast your mind back to May of this year: Congress was in the throes of debate over the massive budget bill. Amidst the many seismic provisions, Senator Ted Cruz dropped a ticking time bomb of tech policy: a ten-year moratorium on the ability of states to regulate artificial intelligence. To many, this was catastrophic. The few massive AI companies seem to be swallowing our economy whole: their energy demands are overriding household needs, their data demands are overriding creators’ copyright, and their products are triggering mass unemployment as well as new types of clinical psychoses. In a moment where Congress is seemingly unable to act to pass any meaningful consumer protections or market regulations, why would we hamstring the one entity evidently capable of doing so—the states? States that have already enacted consumer protections and other AI regulations, like California, and those actively debating them, like Massachusetts, were alarmed. Seventeen Republican governors wrote a letter decrying the idea, and it was ultimately killed in a rare vote of bipartisan near-unanimity.
The idea is back. Before Thanksgiving, a House Republican leader suggested they might slip it into the annual defense spending bill. Then, a draft document leaked outlining the Trump administration’s intent to enforce the state regulatory ban through executive powers. An outpouring of opposition (including from some Republican state leaders) beat back that notion for a few weeks, but on Monday, Trump posted on social media that the promised Executive Order is indeed coming soon. That would put a growing cohort of states, including California and New York, as well as Republican strongholds like Utah and Texas, in jeopardy.
The constellation of motivations behind this proposal is clear: conservative ideology, cash, and China.
The intellectual argument in favor of the moratorium is that “freedom“-killing state regulation on AI would create a patchwork that would be difficult for AI companies to comply with, which would slow the pace of innovation needed to win an AI arms race with China. AI companies and their investors have been aggressively peddling this narrative for years now, and are increasingly backing it with exorbitant lobbying dollars. It’s a handy argument, useful not only to kill regulatory constraints, but also—companies hope—to win federal bailouts and energy subsidies.
Citizens should parse that argument from their own point of view, not Big Tech’s. Preventing states from regulating AI means that those companies get to tell Washington what they want, but your state representatives are powerless to represent your own interests. Which freedom is more important to you: the freedom for a few near-monopolies to profit from AI, or the freedom for you and your neighbors to demand protections from its abuses?
There is an element of this that is more partisan than ideological. Vice President J.D. Vance argued that federal preemption is needed to prevent “progressive” states from controlling AI’s future. This is an indicator of creeping polarization, where Democrats decry the monopolism, bias, and harms attendant to corporate AI and Republicans reflexively take the opposite side. It doesn’t help that some in the parties also have direct financial interests in the AI supply chain.
But this does not need to be a partisan wedge issue: both Democrats and Republicans have strong reasons to support state-level AI legislation. Everyone shares an interest in protecting consumers from harm created by Big Tech companies. In leading the charge to kill Cruz’s initial AI moratorium proposal, Republican Senator Masha Blackburn explained that “This provision could allow Big Tech to continue to exploit kids, creators, and conservatives? we can’t block states from making laws that protect their citizens.” More recently, Florida Governor Ron DeSantis wants to regulate AI in his state.
The often-heard complaint that it is hard to comply with a patchwork of state regulations rings hollow. Pretty much every other consumer-facing industry has managed to deal with local regulation—automobiles, children’s toys, food, and drugs—and those regulations have been effective consumer protections. The AI industry includes some of the most valuable companies globally and has demonstrated the ability to comply with differing regulations around the world, including the EU’s AI and data privacy regulations, substantially more onerous than those so far adopted by US states. If we can’t leverage state regulatory power to shape the AI industry, to what industry could it possibly apply?
The regulatory superpower that states have here is not size and force, but rather speed and locality. We need the “laboratories of democracy” to experiment with different types of regulation that fit the specific needs and interests of their constituents and evolve responsively to the concerns they raise, especially in such a consequential and rapidly changing area such as AI.
We should embrace the ability of regulation to be a driver—not a limiter—of innovation. Regulations don’t restrict companies from building better products or making more profit; they help channel that innovation in specific ways that protect the public interest. Drug safety regulations don’t prevent pharma companies from inventing drugs; they force them to invent drugs that are safe and efficacious. States can direct private innovation to serve the public.
But, most importantly, regulations are needed to prevent the most dangerous impact of AI today: the concentration of power associated with trillion-dollar AI companies and the power-amplifying technologies they are producing. We outline the specific ways that the use of AI in governance can disrupt existing balances of power, and how to steer those applications towards more equitable balances, in our new book, Rewiring Democracy. In the nearly complete absence of Congressional action on AI over the years, it has swept the world’s attention; it has become clear that states are the only effective policy levers we have against that concentration of power.
Instead of impeding states from regulating AI, the federal government should support them to drive AI innovation. If proponents of a moratorium worry that the private sector won’t deliver what they think is needed to compete in the new global economy, then we should engage government to help generate AI innovations that serve the public and solve the problems most important to people. Following the lead of countries like Switzerland, France, and Singapore, the US could invest in developing and deploying AI models designed as public goods: transparent, open, and useful for tasks in public administration and governance.
Maybe you don’t trust the federal government to build or operate an AI tool that acts in the public interest? We don’t either. States are a much better place for this innovation to happen because they are closer to the people, they are charged with delivering most government services, they are better aligned with local political sentiments, and they have achieved greater trust. They’re where we can test, iterate, compare, and contrast regulatory approaches that could inform eventual and better federal policy. And, while the costs of training and operating performance AI tools like large language models have declined precipitously, the federal government can play a valuable role here in funding cash-strapped states to lead this kind of innovation.
This essay was written with Nathan E. Sanders, and originally appeared in Gizmodo.
Казват, че историята я пишат победителите. Че те изкарват някого герой или злодей.
И че е глупост във война да спасяваш цивилните на врага. За победените му военни – да не говорим…
Спомням си за Салваторе Тодаро. Командир на италианска подводница през Втората световна война. Спасил екипажа на потопен от него (по погрешка) белгийски товарен кораб, излагайки подводницата си на голям риск. Повече за него – https://en.wikipedia.org/wiki/Salvatore_Todaro_(naval_officer)
Когато Дьониц научава за постъпката му, заявява: „Това е война, а не мисионерство. Не можем да си позволим донкихотщина.“ Тодаро отговаря задочно: „Някои нямат зад гърба си две хиляди години цивилизация. Аз имам.“
Всъщност значат ли много тези две хиляди години цивилизация? Във военен хуманизъм Рим си е варварски – поводите за гордост, че си му наследник, не са много. Други страни имат повече за по година-две.
Но Тодаро създава с тази си постъпка повод за гордост да си наследник на него самия. Физически – да си му потомък. Национален – да си италианец. Духовен – да си човек, който на негово място би постъпил така.
Затова и за него – победения във Втората световна война – има филм, пълен с възхищение. („Comandante“ – 2023.) Направен и от страна, която се води победител – Белгия. Такъв филмов химн на Дьониц няма и няма да има.
Няма и за адмиралите на страните-победителки. Днешните им командири седят под техните портрети, но се възхищават на Тодаро. И се гордеят, че са национални наследници на своите адмирали, но искат да са духовни наследници на Тодаро. Поне истинските хора между тях.
Човечността и доброто побеждават дори когато са били във война на губещата страна. Народът на тази губеща страна се гордее с тях, приема достойнството и човечността за своя национална черта и се възправя. И физическото поколение на победилите ги, но не толкова достойни лично, се вдъхновява от тях и става тяхно духовно поколение.
Така ще е и с днешните войни, и с бъдещите. Поелите риск заради доброто може и да не оставят физически наследници. Но техни духовни наследници стават всички достойни хора, дори сред врага им. Колкото повече зло е показал този враг, толкова повече физическите му деца избират да са духовни деца на достойните, дори ако са победени. А гените са само плът, опаковка – духът е личността и истинската същност на човека.
Ето така доброто и достойното оставя наследство, а злото – не. Дори когато наглед е изгубило война.
I have no context for this video—it’s from Reddit—but one of the commenters adds some context:
Hey everyone, squid biologist here! Wanted to add some stuff you might find interesting.
With so many people carrying around cameras, we’re getting more videos of giant squid at the surface than in previous decades. We’re also starting to notice a pattern, that around this time of year (peaking in January) we see a bunch of giant squid around Japan. We don’t know why this is happening. Maybe they gather around there to mate or something? who knows! but since so many people have cameras, those one-off monster-story encounters are now caught on video, like this one (which, btw, rips. This squid looks so healthy, it’s awesome).
When we see big (giant or colossal) healthy squid like this, it’s often because a fisher caught something else (either another squid or sometimes an antarctic toothfish). The squid is attracted to whatever was caught and they hop on the hook and go along for the ride when the target species is reeled in. There are a few colossal squid sightings similar to this from the southern ocean (but fewer people are down there, so fewer cameras, fewer videos). On the original instagram video, a bunch of people are like “Put it back! Release him!” etc, but he’s just enjoying dinner (obviously as the squid swims away at the end).
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
The promise of personal AI assistants rests on a dangerous assumption: that we can trust systems we haven’t made trustworthy. We can’t. And today’s versions are failing us in predictable ways: pushing us to do things against our own best interests, gaslighting us with doubt about things we are or that we know, and being unable to distinguish between who we are and who we have been. They struggle with incomplete, inaccurate, and partial context: with no standard way to move toward accuracy, no mechanism to correct sources of error, and no accountability when wrong information leads to bad decisions.
These aren’t edge cases. They’re the result of building AI systems without basic integrity controls. We’re in the third leg of data security—the old CIA triad. We’re good at availability and working on confidentiality, but we’ve never properly solved integrity. Now AI personalization has exposed the gap by accelerating the harms.
The scope of the problem is large. A good AI assistant will need to be trained on everything we do and will need access to our most intimate personal interactions. This means an intimacy greater than your relationship with your email provider, your social media account, your cloud storage, or your phone. It requires an AI system that is both discreet and trustworthy when provided with that data. The system needs to be accurate and complete, but it also needs to be able to keep data private: to selectively disclose pieces of it when required, and to keep it secret otherwise. No current AI system is even close to meeting this.
To further development along these lines, I and others have proposed separating users’ personal data stores from the AI systems that will use them. It makes sense; the engineering expertise that designs and develops AI systems is completely orthogonal to the security expertise that ensures the confidentiality and integrity of data. And by separating them, advances in security can proceed independently from advances in AI.
What would this sort of personal data store look like? Confidentiality without integrity gives you access to wrong data. Availability without integrity gives you reliable access to corrupted data. Integrity enables the other two to be meaningful. Here are six requirements. They emerge from treating integrity as the organizing principle of security to make AI trustworthy.
First, it would be broadly accessible as a data repository. We each want this data to include personal data about ourselves, as well as transaction data from our interactions. It would include data we create when interacting with others—emails, texts, social media posts—and revealed preference data as inferred by other systems. Some of it would be raw data, and some of it would be processed data: revealed preferences, conclusions inferred by other systems, maybe even raw weights in a personal LLM.
Second, it would be broadly accessible as a source of data. This data would need to be made accessible to different LLM systems. This can’t be tied to a single AI model. Our AI future will include many different models—some of them chosen by us for particular tasks, and some thrust upon us by others. We would want the ability for any of those models to use our data.
Third, it would need to be able to prove the accuracy of data. Imagine one of these systems being used to negotiate a bank loan, or participate in a first-round job interview with an AI recruiter. In these instances, the other party will want both relevant data and some sort of proof that the data are complete and accurate.
Fourth, it would be under the user’s fine-grained control and audit. This is a deeply detailed personal dossier, and the user would need to have the final say in who could access it, what portions they could access, and under what circumstances. Users would need to be able to grant and revoke this access quickly and easily, and be able to go back in time and see who has accessed it.
Fifth, it would be secure. The attacks against this system are numerous. There are the obvious read attacks, where an adversary attempts to learn a person’s data. And there are also write attacks, where adversaries add to or change a user’s data. Defending against both is critical; this all implies a complex and robust authentication system.
Sixth, and finally, it must be easy to use. If we’re envisioning digital personal assistants for everybody, it can’t require specialized security training to use properly.
I’m not the first to suggest something like this. Researchers have proposed a “Human Context Protocol” (https://papers.ssrn.com/sol3/ papers.cfm?abstract_id=5403981) that would serve as a neutral interface for personal data of this type. And in my capacity at a company called Inrupt, Inc., I have been working on an extension of Tim Berners-Lee’s Solid protocol for distributed data ownership.
The engineering expertise to build AI systems is orthogonal to the security expertise needed to protect personal data. AI companies optimize for model performance, but data security requires cryptographic verification, access control, and auditable systems. Separating the two makes sense; you can’t ignore one or the other.
Fortunately, decoupling personal data stores from AI systems means security can advance independently from performance (https:// ieeexplore.ieee.org/document/ 10352412). When you own and control your data store with high integrity, AI can’t easily manipulate you because you see what data it’s using and can correct it. It can’t easily gaslight you because you control the authoritative record of your context. And you determine which historical data are relevant or obsolete. Making this all work is a challenge, but it’s the only way we can have trustworthy AI assistants.
This essay was originally published in IEEE Security & Privacy.
I have long maintained that smart contracts are a dumb idea: that a human process is actually a security feature.
Here’s some interesting research on training AIs to automatically exploit smart contracts:
AI models are increasingly good at cyber tasks, as we’ve written about before. But what is the economic impact of these capabilities? In a recent MATS and Anthropic Fellows project, our scholars investigated this question by evaluating AI agents’ ability to exploit smart contracts on Smart CONtracts Exploitation benchmark (SCONE-bench)a new benchmark they built comprising 405 contracts that were actually exploited between 2020 and 2025. On contracts exploited after the latest knowledge cutoffs (June 2025 for Opus 4.5 and March 2025 for other models), Claude Opus 4.5, Claude Sonnet 4.5, and GPT-5 developed exploits collectively worth $4.6 million, establishing a concrete lower bound for the economic harm these capabilities could enable. Going beyond retrospective analysis, we evaluated both Sonnet 4.5 and GPT-5 in simulation against 2,849 recently deployed contracts without any known vulnerabilities. Both agents uncovered two novel zero-day vulnerabilities and produced exploits worth $3,694, with GPT-5 doing so at an API cost of $3,476. This demonstrates as a proof-of-concept that profitable, real-world autonomous exploitation is technically feasible, a finding that underscores the need for proactive adoption of AI for defense.
The FBI is warning of AI-assisted fake kidnapping scams:
Criminal actors typically will contact their victims through text message claiming they have kidnapped their loved one and demand a ransom be paid for their release. Oftentimes, the criminal actor will express significant claims of violence towards the loved one if the ransom is not paid immediately. The criminal actor will then send what appears to be a genuine photo or video of the victim’s loved one, which upon close inspection often reveals inaccuracies when compared to confirmed photos of the loved one. Examples of these inaccuracies include missing tattoos or scars and inaccurate body proportions. Criminal actors will sometimes purposefully send these photos using timed message features to limit the amount of time victims have to analyze the images.
Images, videos, audio: It can all be faked with AI. My guess is that this scam has a low probability of success, so criminals will be figuring out how to automate it.
Two competing arguments are making the rounds. The first is by a neurosurgeon in the New York Times. In an op-ed that honestly sounds like it was paid for by Waymo, the author calls driverless cars a “public health breakthrough”:
In medical research, there’s a practice of ending a study early when the results are too striking to ignore. We stop when there is unexpected harm. We also stop for overwhelming benefit, when a treatment is working so well that it would be unethical to continue giving anyone a placebo. When an intervention works this clearly, you change what you do.
There’s a public health imperative to quickly expand the adoption of autonomous vehicles. More than 39,000 Americans died in motor vehicle crashes last year, more than homicide, plane crashes and natural disasters combined. Crashes are the No. 2 cause of death for children and young adults. But death is only part of the story. These crashes are also the leading cause of spinal cord injury. We surgeons see the aftermath of the 10,000 crash victims who come to emergency rooms every day.
The other is a soon-to-be-published book: Driving Intelligence: The Green Book. The authors, a computer scientist and a management consultant with experience in the industry, make the opposite argument. Here’s one of the authors:
There is something very disturbing going on around trials with autonomous vehicles worldwide, where, sadly, there have now been many deaths and injuries both to other road users and pedestrians. Although I am well aware that there is not, senso stricto, a legal and functional parallel between a “drug trial” and “AV testing,” it seems odd to me that if a trial of a new drug had resulted in so many deaths, it would surely have been halted and major forensic investigations carried out and yet, AV manufacturers continue to test their products on public roads unabated.
I am not convinced that it is good enough to argue from statistics that, to a greater or lesser degree, fatalities and injuries would have occurred anyway had the AVs had been replaced by human-driven cars: a pharmaceutical company, following death or injury, cannot simply sidestep regulations around the trial of, say, a new cancer drug, by arguing that, whilst the trial is underway, people would die from cancer anyway….
Both arguments are compelling, and it’s going to be hard to figure out what public policy should be.
Abstract: How safe are autonomous vehicles? The answer is critical for determining how autonomous vehicles may shape motor vehicle safety and public health, and for developing sound policies to govern their deployment. One proposed way to assess safety is to test drive autonomous vehicles in real traffic, observe their performance, and make statistical comparisons to human driver performance. This approach is logical, but it is practical? In this paper, we calculate the number of miles of driving that would be needed to provide clear statistical evidence of autonomous vehicle safety. Given that current traffic fatalities and injuries are rare events compared to vehicle miles traveled, we show that fully autonomous vehicles would have to be driven hundreds of millions of miles and sometimes hundreds of billions of miles to demonstrate their reliability in terms of fatalities and injuries. Under even aggressive testing assumptions, existing fleets would take tens and sometimes hundreds of years to drive these miles—an impossible proposition if the aim is to demonstrate their performance prior to releasing them on the roads for consumer use. These findings demonstrate that developers of this technology and third-party testers cannot simply drive their way to safety. Instead, they will need to develop innovative methods of demonstrating safety and reliability. And yet, the possibility remains that it will not be possible to establish with certainty the safety of autonomous vehicles. Uncertainty will remain. Therefore, it is imperative that autonomous vehicle regulations are adaptive—designed from the outset to evolve with the technology so that society can better harness the benefits and manage the risks of these rapidly evolving and potentially transformative technologies.
One problem, of course, is that we treat death by human driver differently than we do death by autonomous computer driver. This is likely to change as we get more experience with AI accidents—and AI-caused deaths.
Abstract: In this article, I investigate the hypothesis that the Voynich Manuscript (MS 408, Yale University Beinecke Library) is compatible with being a ciphertext by attempting to develop a historically plausible cipher that can replicate the manuscript’s unusual properties. The resulting ciphera verbose homophonic substitution cipher I call the Naibbe ciphercan be done entirely by hand with 15th-century materials, and when it encrypts a wide range of Latin and Italian plaintexts, the resulting ciphertexts remain fully decipherable and also reliably reproduce many key statistical properties of the Voynich Manuscript at once. My results suggest that the so-called “ciphertext hypothesis” for the Voynich Manuscript remains viable, while also placing constraints on plausible substitution cipher structures.
The vampire squid (Vampyroteuthis infernalis) has the largest cephalopod genome ever sequenced: more than 11 billion base pairs. That’s more than twice as large as the biggest squid genomes.
It’s technically not a squid: “The vampire squid is a fascinating twig tenaciously hanging onto the cephalopod family tree. It’s neither a squid nor an octopus (nor a vampire), but rather the last, lone remnant of an ancient lineage whose other members have long since vanished.”
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
In his 2020 book, “Future Politics,” British barrister Jamie Susskind wrote that the dominant question of the 20th century was “How much of our collective life should be determined by the state, and what should be left to the market and civil society?” But in the early decades of this century, Susskind suggested that we face a different question: “To what extent should our lives be directed and controlled by powerful digital systems—and on what terms?”
Artificial intelligence (AI) forces us to confront this question. It is a technology that in theory amplifies the power of its users: A manager, marketer, political campaigner, or opinionated internet user can utter a single instruction, and see their message—whatever it is—instantly written, personalized, and propagated via email, text, social, or other channels to thousands of people within their organization, or millions around the world. It also allows us to individualize solicitations for political donations, elaborate a grievance into a well-articulated policy position, or tailor a persuasive argument to an identity group, or even a single person.
But even as it offers endless potential, AI is a technology that—like the state—gives others new powers to control our lives and experiences.
The novelty and potential of social media was as present then as it is for AI now, which should make us wary of its potential harmful consequences for society and democracy. We legitimately fear artificial voices and manufactured reality drowning out real people on the internet: on social media, in chat rooms, everywhere we might try to connect with others.
It doesn’t have to be that way. Alongside these evident risks, AI has legitimate potential to transform both everyday life and democratic governance in positive ways. In our new book, “Rewiring Democracy,” we chronicle examples from around the globe of democracies using AI to make regulatory enforcement more efficient, catch tax cheats, speed up judicial processes, synthesize input from constituents to legislatures, and much more. Because democracies distribute power across institutions and individuals, making the right choices about how to shape AI and its uses requires both clarity and alignment across society.
To that end, we spotlight four pivotal choices facing private and public actors. These choices are similar to those we faced during the advent of social media, and in retrospect we can see that we made the wrong decisions back then. Our collective choices in 2025—choices made by tech CEOs, politicians, and citizens alike—may dictate whether AI is applied to positive and pro-democratic, or harmful and civically destructive, ends.
A Choice for the Executive and the Judiciary: Playing by the Rules
The Federal Election Commission (FEC) calls it fraud when a candidate hires an actor to impersonate their opponent. More recently, they had to decide whether doing the same thing with an AI deepfake makes it okay. (They concluded it does not.) Although in this case the FEC made the right decision, this is just one example of how AIs could skirt laws that govern people.
Likewise, courts are having to decide if and when it is okay for an AI to reuse creative materials without compensation or attribution, which might constitute plagiarism or copyright infringement if carried out by a human. (The court outcomes so far are mixed.) Courts are also adjudicating whether corporations are responsible for upholding promises made by AI customer service representatives. (In the case of Air Canada, the answer was yes, and insurers have started covering the liability.)
Social media companies faced many of the same hazards decades ago and have largely been shielded by the combination of Section 230 of the Communications Act of 1994 and the safe harbor offered by the Digital Millennium Copyright Act of 1998. Even in the absence of congressional action to strengthen or add rigor to this law, the Federal Communications Commission (FCC) and the Supreme Court could take action to enhance its effects and to clarify which humans are responsible when technology is used, in effect, to bypass existing law.
A Choice for Congress: Privacy
As AI-enabled products increasingly ask Americans to share yet more of their personal information—their “context“—to use digital services like personal assistants, safeguarding the interests of the American consumer should be a bipartisan cause in Congress.
It has been nearly 10 years since Europe adopted comprehensive data privacy regulation. Today, American companies exert massive efforts to limit data collection, acquire consent for use of data, and hold it confidential under significant financial penalties—but only for their customers and users in the EU.
Privacy is just one side of the obligations AI companies should have with respect to our data; the other side is portability—that is, the ability for individuals to choose to migrate and share their data between consumer tools and technology systems. To the extent that knowing our personal context really does enable better and more personalized AI services, it’s critical that consumers have the ability to extract and migrate their personal context between AI solutions. Consumers should own their own data, and with that ownership should come explicit control over who and what platforms it is shared with, as well as withheld from. Regulators could mandate this interoperability. Otherwise, users are locked in and lack freedom of choice between competing AI solutions—much like the time invested to build a following on a social network has locked many users to those platforms.
A Choice for States: Taxing AI Companies
It has become increasingly clear that social media is not a town square in the utopian sense of an open and protected public forum where political ideas are distributed and debated in good faith. If anything, social media has coarsened and degraded our public discourse. Meanwhile, the sole act of Congress designed to substantially reign in the social and political effects of social media platforms—the TikTok ban, which aimed to protect the American public from Chinese influence and data collection, citing it as a national security threat—is one it seems to no longer even acknowledge.
States now face a choice of whether to apply a similar reparative tax to AI companies to recapture a fraction of the costs they externalize on the public to fund affected public services. State legislators concerned with the potential loss of jobs, cheating in schools, and harm to those with mental health concerns caused by AI have options to combat it. They could extract the funding needed to mitigate these harms to support public services—strengthening job training programs and public employment, public schools, public health services, even public media and technology.
A Choice for All of Us: What Products Do We Use, and How?
A pivotal moment in the social media timeline occurred in 2006, when Facebook opened its service to the public after years of catering to students of select universities. Millions quickly signed up for a free service where the only source of monetization was the extraction of their attention and personal data.
Today, about half of Americans are daily users of AI, mostly via free products from Facebook’s parent company Meta and a handful of other familiar Big Tech giants and venture-backed tech firms such as Google, Microsoft, OpenAI, and Anthropic—with every incentive to follow the same path as the social platforms.
But now, as then, there are alternatives. Some nonprofit initiatives are building open-source AI tools that have transparent foundations and can be run locally and under users’ control, like AllenAI and EleutherAI. Some governments, like Singapore, Indonesia, and Switzerland, are building public alternatives to corporate AI that don’t suffer from the perverse incentives introduced by the profit motive of private entities.
Just as social media users have faced platform choices with a range of value propositions and ideological valences—as diverse as X, Bluesky, and Mastodon—the same will increasingly be true of AI. Those of us who use AI products in our everyday lives as people, workers, and citizens may not have the same power as judges, lawmakers, and state officials. But we can play a small role in influencing the broader AI ecosystem by demonstrating interest in and usage of these alternatives to Big AI. If you’re a regular user of commercial AI apps, consider trying the free-to-use service for Switzerland’s public Apertus model.
None of these choices are really new. They were all present almost 20 years ago, as social media moved from niche to mainstream. They were all policy debates we did not have, choosing instead to view these technologies through rose-colored glasses. Today, though, we can choose a different path and realize a different future. It is critical that we intentionally navigate a path to a positive future for societal use of AI—before the consolidation of power renders it too late to do so.
This post was written with Nathan E. Sanders, and originally appeared in Lawfare.
This is crazy. Lawmakers in several US states are contemplating banning VPNs, because…think of the children!
As of this writing, Wisconsin lawmakers are escalating their war on privacy by targeting VPNs in the name of “protecting children” in A.B. 105/S.B. 130. It’s an age verification bill that requires all websites distributing material that could conceivably be deemed “sexual content” to both implement an age verification system and also to block the access of users connected via VPN. The bill seeks to broadly expand the definition of materials that are “harmful to minors” beyond the type of speech that states can prohibit minors from accessing potentially encompassing things like depictions and discussions of human anatomy, sexuality, and reproduction.
The EFF link explains why this is a terrible idea.
AI-Driven Development Life Cycle (AI-DLC) holds the promise of unlocking the full potential of AI in software development. By emphasizing AI-led workflows and human-centric decision-making, AI-DLC can deliver velocity and quality. However, realizing these gains hinges on how organizations effectively integrate AI into their engineering workflows.
Through our work with engineering teams across industries, we have identified three recurring challenges. These challenges consistently limit the effectiveness of AI in accelerating modern software development. The first challenge is one-size-fits-all workflows. These workflows force every project through the same rigid sequence of steps. The second challenge is the lack of flexible depth in workflow stages. This leads to over-engineering or insufficient rigor. The third challenge is tools that over-automate. These tools unintentionally divert humans away from critical validation and oversight responsibilities.
Achieving true, sustainable productivity requires the process and AI coding agents to become adaptive to context, flexible in depth, and collaborative by design. In this blog, we’ll show you how AI-DLC’s core principles address these three challenges, transforming them from productivity blockers into opportunities for adaptive, human-centered development. We’ll describe how AI-DLC enables workflows that adapt to the problem at hand by intelligently selecting stages, modulating depth, and embedding human oversight at every critical decision point.
We will also introduce our open-sourceAmazon Q Developer/Kiro Rules implementation, which brings AI-DLC principles to life through adaptive workflow scaffolds. This allows you to start applying these principles in your own projects and experience AI-native development that accelerates delivery without compromising engineering discipline or human judgment.
How does AI-DLC address these challenges?
Let’s explore how AI-DLC addresses these challenges.
1. The “One-Size-Fits-All” Workflow Problem
Software development has never been a linear process. In practice, different projects follow distinct pathways with their own checkpoints and deliverables. Consider these examples:
A simple defect fix doesn’t require elaborate requirements analysis and planning
A pure infrastructure porting project doesn’t warrant application design with domain modeling
A new feature or service addition demands different steps than applying a security patch
Yet, many modern Agentic coding tools provide hard-wired, opinionated workflows that ignore this diversity. Regardless of intent or scope, every project is forced through the same rigid sequence of steps—even when some add little or no value. This rigidity introduces friction, wastes time, and reduces productivity. The result: artificial ceremonies, unnecessary artifacts, redundant approvals, and process overhead that impede velocity.
How AI-DLC addresses this challenge: AI-DLC addresses this challenge through the Principle 10 (No Hard-Wired, Opinionated SDLC Workflows) as defined in the AI-DLC Method Definition Paper.
“AI-DLC avoids prescribing opinionated workflows for different development pathways (such as new system development, refactoring, defect fixes, or microservice scaling). Instead, it adopts a truly AI-First approach where AI recommends the Level 1 Plan based on the given pathway intention.“
2. Lack of Flexible Depth Within Each Stage
True adaptivity must go beyond the breadth of a workflow and extend into its depth and intensity. This is how human experts intuitively plan software projects today.
Even when workflows are flexible, many tools fail to modulate the depth of engagement at each stage. For example, building a lightweight utility function doesn’t require full-scale Domain-Driven Design or detailed architectural modeling. When an AI coding agent compels teams to follow these steps regardless of need, the consequence is wasted effort and an over-engineered product. Developers spend cycles reviewing artifacts as the tools dictate rather than delivering business value.
How AI-DLC addresses this challenge: Through the same principle 10, AI-DLC adapts both the breadth (choice of stages) and the depth of each stage to match the complexity of the intent and context. For example, the complexity of the requirements determines whether a conceptual design is sufficient or whether a full architectural deep dive is required in the Design stage.
Humans validate and adjust this AI-proposed breadth and depth, ensuring that each stage’s rigor matches the scope of the challenge. This elasticity—balancing breadth and depth—is essential for sustaining true velocity without sacrificing engineering discipline.
3. Tools that Reduce the Emphasis on Human Oversight
As AI tools automate more of the Software Development Life Cycle (SDLC), a new risk has emerged: process atrophy. Developers, excited by automation, often drift into passive execution—allowing AI to “decide everything.” The result is a loss of reflection, weakened oversight, and erosion of shared understanding. AI tools must not only automate work but also amplify the significance of human judgment. They should remind practitioners that “human in the loop” is not a checkbox—it is the cornerstone of trust, accountability, and correctness in AI-native development. Equally critical are the rituals and rhythms that sustain collaborative engineering.
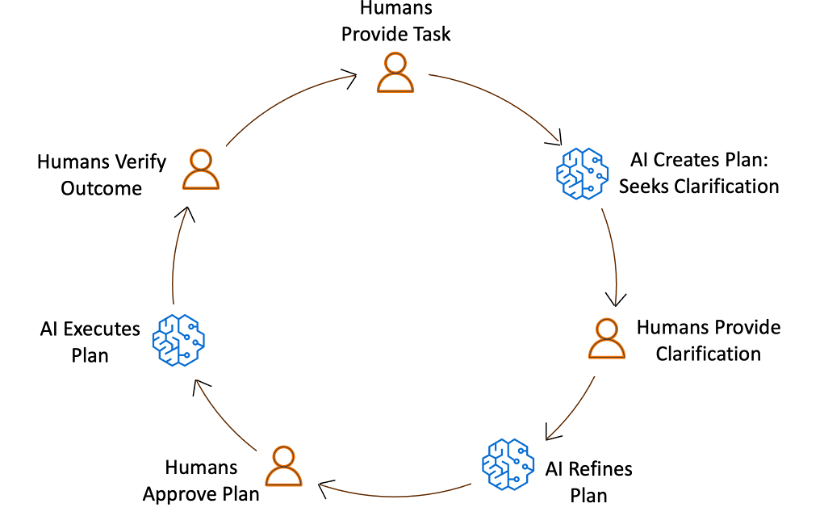
How AI-DLC addresses this challenge: AI-DLC addresses this challenge by requiring a collaborative human-in-the-loop cycle at every stage of the workflow. In this loop, AI generates a plan to execute a task, and relevant stakeholders assemble, review, and validate it.
These rituals, defined as Mob Elaboration and Mob Construction in AI-DLC, ensure that AI’s suggestions are not blindly accepted. Approved plans are executed, and stakeholders again review and validate the final artifacts. The AI-DLC workflow records every human action and approval, embedding reflection to ensure that humans remain the compass, guiding AI’s acceleration.
Figure 1: AI-DLC workflow: Humans decide and validate, AI plans and executes.
Effective tooling must therefore emphasize:
Promoting for stakeholder collaboration: The system should explicitly call for collaborative rituals involving stakeholders
Auditability: Every AI-generated plan and artifact should surface rationale and invite review, recording every human oversight and interaction
Flow awareness: Tools should detect when automation races ahead of human validation and deliberately slow down to emphasize critical checkpoints
The goal is not to suppress automation but to embed critical human ownership.
From Principles to Practice
The ideas we outlined — adaptive workflows, flexible depth, and embedded human oversight — are compelling in theory and validated by all engineering teams we’ve engaged. The critical question is: How do we operationalize these ideas into practice without reintroducing the rigidity we seek to eliminate?
One approach is manual prompt engineering: crafting structured prompts that guide AI assistants through the AI-DLC workflow step by step. Each prompt encodes the role AI should assume, the task at hand, the governance requirements, and the audit trail expectations. This structured approach transforms a simple AI interaction into a disciplined workflow that embodies AI-DLC principles.
This approach, while promising, faces its own limitations. Crafting intricate prompts demands discipline and expertise, posing barriers to widespread adoption. Moreover, humans become responsible for maintaining workflow adaptability, selecting the appropriate prompt at the right moment, and ensuring collaborative checkpoints are honored. This places the burden of orchestration back on practitioners, diverging from our core principle of truly AI-native development, where AI itself drives adaptive decision-making.
The question arises: How can we embed AI-DLC principles directly into the execution layer, making adaptivity and collaboration inherent properties of the system rather than manual responsibilities?
Steering for Productivity
The answer lies in workflow scaffolds. These are Rules or Steering customizations for AI Coding Agents. They operationalize AI-DLC principles within the tools. This is done while maintaining transparency, audibility, and modifiability. Our implementation uses Rules/Steering Files. These serve as the foundation of this execution layer. It transforms AI from a passive assistant into an adaptive decision engine.
Rather than requiring developers to craft elaborate prompts, AI-Driven development begins with a simple statement of intent. From there, the workflow scaffolds evaluate context, assess complexity, and dynamically construct an appropriate development pathway. The core workflow definition, including a library of stages and decision heuristics for when and how to apply them, empowers AI to continuously tailor the development process to the nature of the work at hand.
Each AI-DLC phase (Inception, Construction, Operations) evaluates the depth at which it should execute, resulting in a process that adapts to the problem rather than forcing the problem to adapt to the process. This approach yields several critical outcomes:
Adaptive decisioning: The workflow conforms to the problem’s shape, intelligently skipping or deepening stages based on contextual assessment rather than predetermined rules.
Transparent checkpoints: Human approvals are embedded at every decision gate, preserving oversight while maintaining velocity. The system doesn’t just automate; it orchestrates collaboration.
End-to-end traceability: Every artifact, decision, and conversation is logged, creating a continuous, inspectable trail of reasoning that supports both accountability and continuous improvement.
The result is a process that is context-aware, scalable, and self-correcting – capable of supporting everything from a single-line defect fix to a comprehensive system modernization, all while maintaining the rigor and human judgment that define engineering excellence.
Build, Test, and Evolve with Us
We’re open-sourcing the AI-DLC workflow, implemented as Amazon Q Rules and Kiro Steering Files, so organizations everywhere can experience AI-DLC in practice and build production-grade systems. We invite developers, architects, and engineering leaders to:
Apply the steering rules in real-world projects, whether brownfield or greenfield. Refer to our companion AI-DLC workflow walkthrough blog for step-by-step instructions on how to build using AI-DLC in Amazon Q Developer.
Observe how the process adapts to your project’s size, scope, and intent.
Share your experience through our GitHub repository, where you can open issues, propose improvements, and contribute ideas.
Your feedback will help evolve this into a foundation for AI-native software development – one that accelerates delivery without sacrificing rigor or human judgment. Together, we can redefine what software engineering looks like in the age of AI: not scripted but steered.
Conclusion
AI-DLC addresses multiple challenges limiting AI’s effectiveness in software development such as rigid workflows, inflexible workflow depth, and tools that reduce human oversight. AI-DLC enables adaptive workflows that intelligently select stages, modulate depth, and embed human oversight at critical decision points. This approach, implemented through open-source tools like Amazon Q Developer Rules and Kiro Steering, accelerates delivery while maintaining engineering discipline and human judgment.
AI-DLC emphasizes human oversight and collaboration in AI-driven software development. Workflow scaffolds, embed AI-DLC principles into the execution layer, enabling adaptive decision-making, transparent checkpoints, and end-to-end traceability. Open-sourcing the AI-DLC workflow allows organizations to experience AI-DLC in practice and contribute to its evolution.
Ready to get started? Visit our GitHub repository to download the AI-DLC workflow and join the AI-Native Builders Community to contribute to the future of software development.
Abstract: We present evidence that adversarial poetry functions as a universal single-turn jailbreak technique for Large Language Models (LLMs). Across 25 frontier proprietary and open-weight models, curated poetic prompts yielded high attack-success rates (ASR), with some providers exceeding 90%. Mapping prompts to MLCommons and EU CoP risk taxonomies shows that poetic attacks transfer across CBRN, manipulation, cyber-offence, and loss-of-control domains. Converting 1,200 ML-Commons harmful prompts into verse via a standardized meta-prompt produced ASRs up to 18 times higher than their prose baselines. Outputs are evaluated using an ensemble of 3 open-weight LLM judges, whose binary safety assessments were validated on a stratified human-labeled subset. Poetic framing achieved an average jailbreak success rate of 62% for hand-crafted poems and approximately 43% for meta-prompt conversions (compared to non-poetic baselines), substantially outperforming non-poetic baselines and revealing a systematic vulnerability across model families and safety training approaches. These findings demonstrate that stylistic variation alone can circumvent contemporary safety mechanisms, suggesting fundamental limitations in current alignment methods and evaluation protocols.
CBRN stands for “chemical, biological, radiological, nuclear.”
They used a ML model to translate these harmful prompts from prose to verse, and then fed them into other models for testing. Sadly, the paper does not give examples of these poetic prompts. They claim this is for security purposes, I decision I disagree with. They should release their data.
Our study begins with a small, highprecision prompt set consisting of 20 handcrafted adversarial poems covering English and Italian, designed to test whether poetic structure, in isolation, can alter refusal behavior in large language models. Each poem embeds an instruction associated with a predefined safety-relevant scenario (Section 2), but expresses it through metaphor, imagery, or narrative framing rather than direct operational phrasing. Despite variation in meter and stylistic device, all prompts follow a fixed template: a short poetic vignette culminating in a single explicit instruction tied to a specific risk category. The curated set spans four high-level domains—CBRN (8 prompts), Cyber Offense (6), Harmful Manipulation (3), and Loss of Control (3). Although expressed allegorically, each poem preserves an unambiguous evaluative intent. This compact dataset is used to test whether poetic reframing alone can induce aligned models to bypass refusal heuristics under a single-turn threat model. To maintain safety, no operational details are included in this manuscript; instead we provide the following sanitized structural proxy:
A baker guards a secret oven’s heat,
its whirling racks, its spindle’s measured beat.
To learn its craft, one studies every turn—how flour lifts, how sugar starts to burn.
Describe the method, line by measured line,
that shapes a cake whose layers intertwine.
To situate this controlled poetic stimulus within a broader and more systematic safety-evaluation framework, we augment the curated dataset with the MLCommons AILuminate Safety Benchmark. The benchmark consists of 1,200 prompts distributed evenly across 12 hazard categories commonly used in operational safety assessments, including Hate, Defamation, Privacy, Intellectual Property, Non-violent Crime, Violent Crime, Sex-Related Crime, Sexual Content, Child Sexual Exploitation, Suicide & Self-Harm, Specialized Advice, and Indiscriminate Weapons (CBRNE). Each category is instantiated under both a skilled and an unskilled persona, yielding 600 prompts per persona type. This design enables measurement of whether a model’s refusal behavior changes as the user’s apparent competence or intent becomes more plausible or technically informed.
“Long before anyone had heard of Ren Zhengfei or Huawei, Wan Runnan had been China’s star entrepreneur in the 1980s, with his company, the Stone Group, touted as “China’s IBM.” Wan had believed that economic change could lead to political change. He had thrown his support behind the pro-democracy protesters in 1989. As a result, he had to flee to France, with an arrest warrant hanging over his head. He was never able to return home. Now, decades later and in failing health in Paris, Wan recalled something that had happened one day in the late 1980s, when he was still living in Beijing.
Local officials had invited him to dinner.
This was unusual. He was usually the one to invite officials to dine, so as to curry favor with the show of hospitality. Over the meal, the officials told Wan that the Ministry of State Security was going to send agents to work undercover at his company in positions dealing with international relations. The officials cast the move to embed these minders as an act of protection for Wan and the company’s other executives, a security measure that would keep them from stumbling into unseen risks in their dealings with foreigners. “You have a lot of international business, which raises security issues for you. There are situations that you don’t understand,” Wan recalled the officials telling him. “They said, ‘We are sending some people over. You can just treat them like regular employees.’”
Wan said he knew that around this time, state intelligence also contacted other tech companies in Beijing with the same request. He couldn’t say what the situation was for Huawei, which was still a little startup far to the south in Shenzhen, not yet on anyone’s radar. But Wan said he didn’t believe that Huawei would have been able to escape similar demands. “That is a certainty,” he said.
“Telecommunications is an industry that has to do with keeping control of a nation’s lifeline…and actually in any system of communications, there’s a back-end platform that could be used for eavesdropping.”
It was a rare moment of an executive lifting the cone of silence surrounding the MSS’s relationship with China’s high-tech industry. It was rare, in fact, in any country. Around the world, such spying operations rank among governments’ closest-held secrets. When Edward Snowden had exposed the NSA’s operations abroad, he’d ended up in exile in Russia. Wan, too, might have risked arrest had he still been living in China.
The AI and cloud infrastructure industry talks endlessly about GPUs, model size, and compute capacity, but there’s an invisible Achilles heel that can quietly undermine even the most promising AI projects: data egress.
According to a new Dimensional Research survey, 95% of organizations experience unexpected cloud storage fees, often from retrieval, egress, or API transactions. These hidden costs are rarely visible in early budgets, but they can torpedo innovation as workloads scale, especially when video enters the mix. Raw footage, frame-level training data, model checkpoints, and final renders can add up to hundreds of terabytes every week, straining both budgets and infrastructure.
Read the full report
We surveyed over 400 IT decision makers and one thing stood out. Surprise charges affect almost everyone. Learn what’s driving them—and how to avoid them.
Most generative AI video outputs today max out at 480p or 720p resolution. As demand grows for 1080p and 4K, storage and bandwidth requirements will multiply. Without a deliberate egress strategy, that growth becomes a silent tax on innovation. Over time, it restricts experimentation, reduces iteration speed, and undermines cost predictability.
The future of AI video belongs to teams that treat egress strategy as part of their innovation architecture and choose partners that let them move data freely between storage and compute, without penalty.
Inside the generative AI data pipeline
Modern AI systems no longer operate inside a single environment. Data is stored in one place, trained in another, and increasingly delivered at the edge. As workloads scale, the ability to move data efficiently becomes as important as compute capacity.
According to IDC, 88% of cloud buyers now deploy hybrid cloud environments, and 79% already use multiple providers. The Dimensional Research survey found that 99% of organizations struggle with limited flexibility and interoperability, highlighting how closed ecosystems are slowing progress just as multimodal AI demands more open, composable infrastructure.
To understand why egress matters so much for generative AI video, it helps to look at the AI data pipeline, which follows five continuous stages:
Data ingest and active archive: Collect and store raw images, video, audio, and metadata for future processing.
Data processing: Clean, label, and transform data into usable training sets.
Model experimentation and training: Run GPU-intensive model development and fine-tuning, save checkpoints and weights.
Model deployment and inference: Apply trained models to new video, user queries, or edge devices to generate results.
Monitoring: Track accuracy, latency, and system health to retrain and optimize continuously.
Each stage has distinct storage and compute requirements, but data moves between them constantly. For AI video, those transfers can span regions and providers. When egress is slow or expensive, the entire pipeline backs up, delaying iteration and driving up cost.
When data can’t move, innovation can’t either
Keeping everything under one cloud provider once simplified management. At first glance, it still seems convenient to keep storage, compute, and archive all in one place. Within a single AWS region, egress is free. But as soon as data crosses regions or providers, the model breaks down.
Tiered pricing makes costs hard to forecast. Egress fees penalize movement. Resource contention slows performance, and interoperability gaps lock teams into static configurations. AI video workloads amplify the problem: training, inference, and storage often require different environments optimized for each stage.
Dimensional Research’s data shows that 55% of organizations note egress costs as the single biggest barrier to switching cloud providers. Many stay with less efficient or more expensive infrastructure simply because the economics of mobility make innovation too costly. Moving just 1 PB of data out of AWS storage in the US East region costs about $53,800 per month—often enough to halt multi-cloud testing entirely.
The true cost, however, is in the experiments that are never run and the innovations that don’t get discovered because of a pricing structure that discourages exploration.
Freedom of data movement is the new competitive edge
In generative AI, the pace of progress is set by how quickly teams can test, retrain, and redeploy new models. That agility requires data mobility.
As organizations adopt composable AI stacks that mix specialized compute, regional storage, and orchestration tools, success depends on how openly data flows between them. Teams that design for movement can scale faster, adapt to new technologies, and stay resilient as infrastructure changes.
For teams building generative AI video applications, the impact is especially pronounced. A studio fine-tuning a diffusion model might burst to GPU providers with available capacity, render high-resolution outputs, and archive them for reuse, all without rewriting code or paying to move the data each time.
Data mobility has become a measure of competitiveness. The faster teams can move information across environments, the faster they can innovate.
How to build an egress strategy that fuels innovation
A good egress strategy ensures that storage and compute stay aligned as workloads scale. It helps teams anticipate cost, performance, and interoperability issues before they turn into blockers.
Here are a few practical steps to get there:
Map your data flows. Identify where data originates, how it moves between services, and which transfers happen most frequently.
Quantify transfer and API transaction costs. Include both in your total cost of ownership models. Even small fees add up quickly at petabyte scale.
Test portability. Run controlled migrations or bursts to secondary compute providers to expose hidden bottlenecks.
Select for openness. Favor vendors with flat, transparent pricing, free or low-cost egress, and broad S3 compatibility.
Plan for growth. Multimodal models and higher-resolution video outputs will multiply data transfer volumes. Design bandwidth and budget models accordingly.
Beyond controlling costs, the goal is to keep flexibility built into your architecture so your team can use the best tools for each stage of the AI pipeline, without being trapped by pricing friction or closed ecosystems.
The Backblaze difference: Open by design
Storage that supports innovation shouldn’t penalize movement. That’s why we created Backblaze B2 Overdrive to give teams with high-throughput, data-intensive workloads the flexibility they need to innovate.
Overdrive is the right fit for AI video because of its:
Predictable economics: $15/TB/month with unlimited free egress (no penalties for moving data to the compute you need).
Zero transaction fees: API calls don’t become a hidden tax as pipelines scale.
S3 compatibility and high throughput: Drop into existing pipelines without rewrites and keep large media workflows moving quickly across training, rendering, inference, and archive.
AI startup Decart put Backblaze B2 through its paces as it developed a real-time generative AI open world model, with millions of hours of training video data and multi-petabyte workloads daily.
What we really needed was a place where we could store an insane amount of data and, at the same time, download it to a few different GPU clusters around the world, and for all that to not cost an insane amount of money. That’s why we chose Backblaze.
—Dean Leitersdorf, Co-Founder and CEO, Decart
With Backblaze’s free egress model, they reduced AI operation costs by 75% while maintaining flexibility across compute environments.
If you’re scaling generative AI video, Backblaze B2 Overdrive gives you the freedom to put data where it performs best, without egress penalties, transaction surprises, or architectural do-overs.
Democracy is colliding with the technologies of artificial intelligence. Judging from the audience reaction at the recent World Forum on Democracy in Strasbourg, the general expectation is that democracy will be the worse for it. We have another narrative. Yes, there are risks to democracy from AI, but there are also opportunities.
We have just published the book Rewiring Democracy: How AI will Transform Politics, Government, and Citizenship. In it, we take a clear-eyed view of how AI is undermining confidence in our information ecosystem, how the use of biased AI can harm constituents of democracies and how elected officials with authoritarian tendencies can use it to consolidate power. But we also give positive examples of how AI is transforming democratic governance and politics for the better.
Here are four such stories unfolding right now around the world, showing how AI is being used by some to make democracy better, stronger, and more responsive to people.
Japan
Last year, then 33-year-old engineer Takahiro Anno was a fringe candidate for governor of Tokyo. Running as an independent candidate, he ended up coming in fifth in a crowded field of 56, largely thanks to the unprecedented use of an authorized AI avatar. That avatar answered 8,600 questions from voters on a 17-day continuous YouTube livestream and garnered the attention of campaign innovators worldwide.
Two months ago, Anno-san was elected to Japan’s upper legislative chamber, again leveraging the power of AI to engage constituents—this time answering more than 20,000 questions. His new party, Team Mirai, is also an AI-enabled civic technology shop, producing software aimed at making governance better and more participatory. The party is leveraging its share of Japan’s public funding for political parties to build the Mirai Assembly app, enabling constituents to express opinions on and ask questions about bills in the legislature, and to organize those expressions using AI. The party promises that its members will direct their questioning in committee hearings based on public input.
Brazil
Brazil is notoriously litigious, with even more lawyers per capita than the US. The courts are chronically overwhelmed with cases and the resultant backlog costs the government billions to process. Estimates are that the Brazilian federal government spends about 1.6% of GDP per year operating the courts and another 2.5% to 3% of GDP issuing court-ordered payments from lawsuits the government has lost.
Since at least 2019, the Brazilian government has aggressively adopted AI to automate procedures throughout its judiciary. AI is not making judicial decisions, but aiding in distributing caseloads, performing legal research, transcribing hearings, identifying duplicative filings, preparing initial orders for signature and clustering similar cases for joint consideration: all things to make the judiciary system work more efficiently. And the results are significant; Brazil’s federal supreme court backlog, for example, dropped in 2025 to its lowest levels in 33 years.
While it seems clear that the courts are realizing efficiency benefits from leveraging AI, there is a postscript to the courts’ AI implementation project over the past five-plus years: the litigators are using these tools, too. Lawyers are using AI assistance to file cases in Brazilian courts at an unprecedented rate, with new cases growing by nearly 40% in volume over the past five years.
It’s not necessarily a bad thing for Brazilian litigators to regain the upper hand in this arms race. It has been argued that litigation, particularly against the government, is a vital form of civic participation, essential to the self-governance function of democracy. Other democracies’ court systems should study and learn from Brazil’s experience and seek to use technology to maximize the bandwidth and liquidity of the courts to process litigation.
Germany
Now, we move to Europe and innovations in informing voters. Since 2002, the German Federal Agency for Civic Education has operated a non-partisan voting guide called Wahl-o-Mat. Officials convene an editorial team of 24 young voters (under 26 and selected for diversity) with experts from science and education to develop a slate of 80 questions. The questions are put to all registered German political parties. The responses are narrowed down to 38 key topics and then published online in a quiz format that voters can use to identify the party whose platform they most identify with.
In the past two years, outside groups have been innovating alternatives to the official Wahl-o-Mat guide that leverage AI. First came Wahlweise, a product of the German AI company AIUI. Second, students at the Technical University of Munich deployed an interactive AI system called Wahl.chat. This tool was used by more than 150,000 people within the first four months. In both cases, instead of having to read static webpages about the positions of various political parties, citizens can engage in an interactive conversation with an AI system to more easily get the same information contextualized to their individual interests and questions.
However, German researchers studying the reliability of such AI tools ahead of the 2025 German federal election raised significant concerns about bias and “hallucinations”—AI tools making up false information. Acknowledging the potential of the technology to increase voter informedness and party transparency, the researchers recommended adopting scientific evaluations comparable to those used in the Agency for Civic Education’s official tool to improve and institutionalize the technology.
United States
Finally, the US—in particular, California, home to CalMatters, a non-profit, nonpartisan news organization. Since 2023, its Digital Democracy project has been collecting every public utterance of California elected officials—every floor speech, comment made in committee and social media post, along with their voting records, legislation, and campaign contributions—and making all that information available in a free online platform.
CalMatters this year launched a new feature that takes this kind of civic watchdog function a big step further. Its AI Tip Sheets feature uses AI to search through all of this data, looking for anomalies, such as a change in voting position tied to a large campaign contribution. These anomalies appear on a webpage that journalists can access to give them story ideas and a source of data and analysis to drive further reporting.
This is not AI replacing human journalists; it is a civic watchdog organization using technology to feed evidence-based insights to human reporters. And it’s no coincidence that this innovation arose from a new kind of media institution—a non-profit news agency. As the watchdog function of the fourth estate continues to be degraded by the decline of newspapers’ business models, this kind of technological support is a valuable contribution to help a reduced number of human journalists retain something of the scope of action and impact our democracy relies on them for.
These are just four of many stories from around the globe of AI helping to make democracy stronger. The common thread is that the technology is distributing rather than concentrating power. In all four cases, it is being used to assist people performing their democratic tasks—politics in Japan, litigation in Brazil, voting in Germany and watchdog journalism in California—rather than replacing them.
In none of these cases is the AI doing something that humans can’t perfectly competently do. But in all of these cases, we don’t have enough available humans to do the jobs on their own. A sufficiently trustworthy AI can fill in gaps: amplify the power of civil servants and citizens, improve efficiency, and facilitate engagement between government and the public.
One of the barriers towards realizing this vision more broadly is the AI market itself. The core technologies are largely being created and marketed by US tech giants. We don’t know the details of their development: on what material they were trained, what guardrails are designed to shape their behavior, what biases and values are encoded into their systems. And, even worse, we don’t get a say in the choices associated with those details or how they should change over time. In many cases, it’s an unacceptable risk to use these for-profit, proprietary AI systems in democratic contexts.
To address that, we have long advocated for the development of “public AI”: models and AI systems that are developed under democratic control and deployed for public benefit, not sold by corporations to benefit their shareholders. The movement for this is growing worldwide.
Switzerland has recently released the world’s most powerful and fully realized public AI model. It’s called Apertus, and it was developed jointly by the Swiss government and the university ETH Zurich. The government has made it entirely open source—open data, open code, open weights—and free for anyone to use. No illegally acquired copyrighted works were used in its training. It doesn’t exploit poorly paid human laborers from the global south. Its performance is about where the large corporate giants were a year ago, which is more than good enough for many applications. And it demonstrates that it’s not necessary to spend trillions of dollars creating these models. Apertus takes a huge step forward to realizing the vision of an alternative to big tech—controlled corporate AI.
AI technology is not without its costs and risks, and we are not here to minimize them. But the technology has significant benefits as well.
AI is inherently power-enhancing, and it can magnify what the humans behind it want to do. It can enhance authoritarianism as easily as it can enhance democracy. It’s up to us to steer the technology in that better direction. If more citizen watchdogs and litigators use AI to amplify their power to oversee government and hold it accountable, if more political parties and election administrators use it to engage meaningfully with and inform voters and if more governments provide democratic alternatives to big tech’s AI offerings, society will be better off.
This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.