Tag Archives: Uncategorized

IACR Nullifies Election Because of Lost Decryption Key

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/iacr-nullifies-election-because-of-lost-decryption-key.html

The International Association of Cryptologic Research—the academic cryptography association that’s been putting conferences like Crypto (back when “crypto” meant “cryptography”) and Eurocrypt since the 1980s—had to nullify an online election when trustee Moti Yung lost his decryption key.

For this election and in accordance with the bylaws of the IACR, the three members of the IACR 2025 Election Committee acted as independent trustees, each holding a portion of the cryptographic key material required to jointly decrypt the results. This aspect of Helios’ design ensures that no two trustees could collude to determine the outcome of an election or the contents of individual votes on their own: all trustees must provide their decryption shares.

Unfortunately, one of the three trustees has irretrievably lost their private key, an honest but unfortunate human mistake, and therefore cannot compute their decryption share. As a result, Helios is unable to complete the decryption process, and it is technically impossible for us to obtain or verify the final outcome of this election.

The group will redo the election, but this time setting a 2-of-3 threshold scheme for decrypting the results, instead of requiring all three

News articles.

Introducing AWS CloudFormation Stack Refactoring Console Experience: Reorganize Your Infrastructure Without Disruption

Post Syndicated from Brian Terry original https://aws.amazon.com/blogs/devops/introducing-aws-cloudformation-stack-refactoring-reorganize-your-infrastructure-without-disruption/

AWS CloudFormation models and provisions cloud infrastructure as code, letting you manage entire lifecycle operations through declarative templates. Stack Refactoring console experience, announced today, extends the AWS CLI experience launched earlier. Now, you move resources between stacks, rename logical IDs, and decompose monolithic templates into focused components without touching the underlying infrastructure using the CloudFormation console. Your resources maintain stability and operational state throughout the reorganization. Whether you’re modernizing legacy stacks, aligning infrastructure with evolving architectural patterns, or improving long-term maintainability, Stack Refactoring adapts your CloudFormation stacks organization to changing requirements without forcing disruptive workarounds.

Stack Refactoring enables you to move resources between stacks, rename logical resource IDs, and split monolithic stacks into smaller, more manageable components—all while maintaining resource stability and preserving your infrastructure’s operational state. If you’re modernizing legacy infrastructure, aligning stack organization with evolving architectural patterns, or improving maintainability across your cloud resources, Stack Refactoring provides the flexibility you need to adapt your CloudFormation organization to changing

How It Works

Stack Refactoring operates through a controlled, multi-phase process designed around resource safety. When you initiate a refactor operation, CloudFormation analyzes both source and destination templates, constructs a detailed execution plan, then orchestrates resource movement without disrupting running infrastructure. Resource mappings define how assets transfer between stacks and how logical IDs should change. CloudFormation handles the orchestration complexity automatically – moving resources from source stacks, updating or creating destination stacks, and preserving all dependency relationships through exports and imports.

Each refactor operation receives a unique Stack Refactor ID for tracking progress, reviewing planned actions before execution, and monitoring the operation from initiation through completion. This preview-then-execute model gives you confidence in complex refactoring scenarios where dependencies span multiple stacks or templates.

Compared to the CLI, the console experience provides an easier way to view refactor actions, get automatic resource mapping, and easily rename logical IDs.

Example Scenario

Scenario 1: Splitting a Monolithic Stack

In this scenario, you have an Amazon Simple Notification Service (SNS) and AWS Lambda Function subscribed to it. As usage patterns evolve, you want to separate the subscriptions into a different stack for better organizational boundaries. You can also rename a resource’s logical ID to improve template clarity or align with naming conventions. Stack Refactoring handles this without recreating the underlying resource.

  1. Create a new template MySNS.yaml using the following :
    # Original stack: MySns
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      Topic:
        Type: AWS::SNS::Topic
    
      MyFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt FunctionRole.Arn
          Timeout: 30
    
      Subscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt MyFunction.Arn
          Protocol: lambda
          TopicArn: !Ref Topic
    
      FunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt MyFunction.Arn
          SourceArn: !Ref Topic
    
      FunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
  2. Create a new stack using this MySNS.yaml template:
    aws cloudformation create-stack --stack-name MySns --template-body file://MySNS.yaml --capabilities CAPABILITY_IAM
  3. Create a new template called afterSns.yaml with the content below. This template has your SNS topic in it and has a new export in it that will export the SNS topic ARN. This export will be used by your other templates to get the required SNS topic ARN.
    # afterSns.yaml - Focused SNS stack
    Resources:
      Topic:
        Type: AWS::SNS::Topic
    Outputs:
      TopicArn:
        Value: !Ref Topic
        Export:
          Name: TopicArn
  4. Create a new template afterLambda.yaml with the following content. This template includes all the resources to create a Lambda subscription to your SNS topic. This template switched the !Ref Topic to use the exported valued by using !ImportValue TopicArn. We are also updating the Logical Resource Id of Lambda function from MyFunction to Function

    AWSTemplateFormatVersion: "2010-09-09"
    Resources:
      Function:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt FunctionRole.Arn
          Timeout: 30
      Subscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt Function.Arn
          Protocol: lambda
          TopicArn: !ImportValue TopicArn
      FunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt Function.Arn
          SourceArn: !ImportValue TopicArn
      FunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow


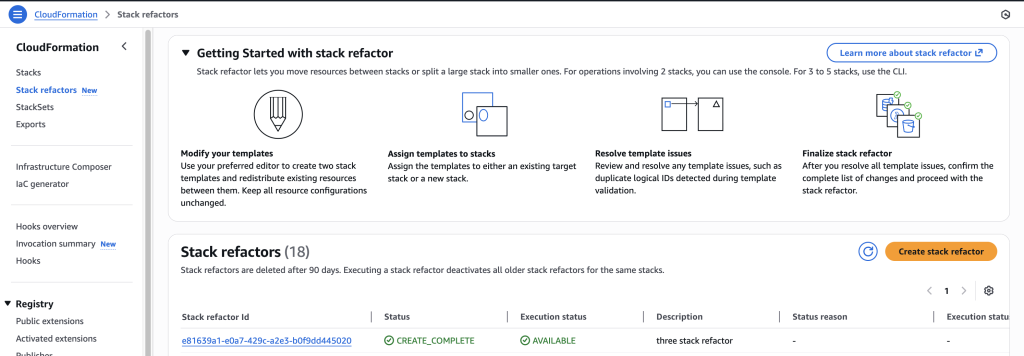
  5. Go to stack refactor home page, click on ‘create stack refactor’
    Go to stack refactor home page, click on ‘create stack refactor’
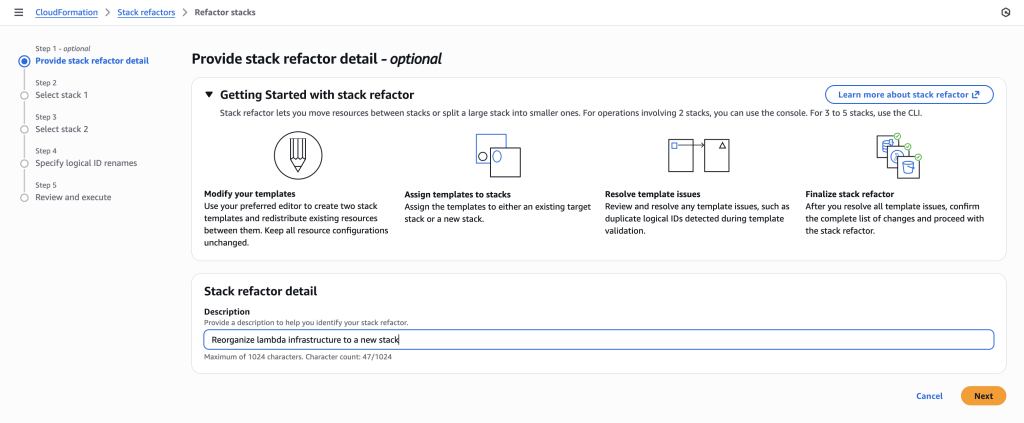
  6. Provide a description to help you identify your stack refactor.
    Provide a description to help you identify your stack refactor.
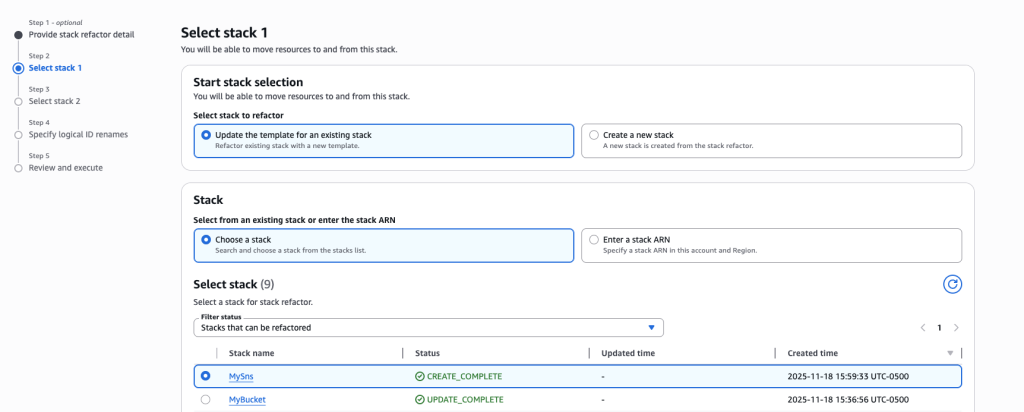
  7. For this scenario, we are splitting a monolithic stack so select ‘Update the template for an existing stack’ and ‘Choose a stack’ options.
  8. Search and choose the stack MySns that was created in Step 1.
    Search and choose the stack MySns that was created in Step 1.
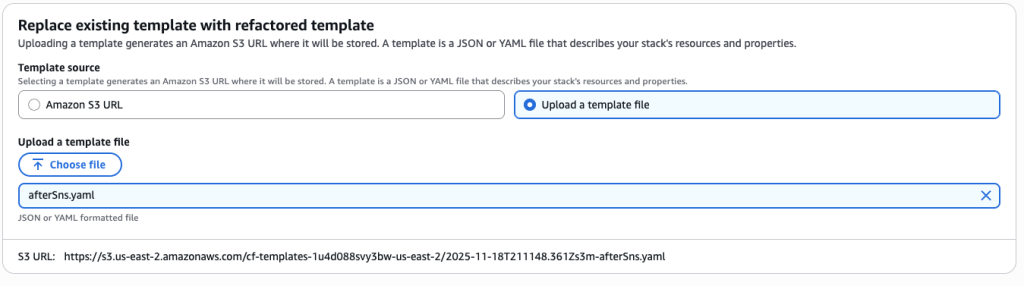
  9. Upload the afterSns.yaml file
    Upload the afterSns.yaml file
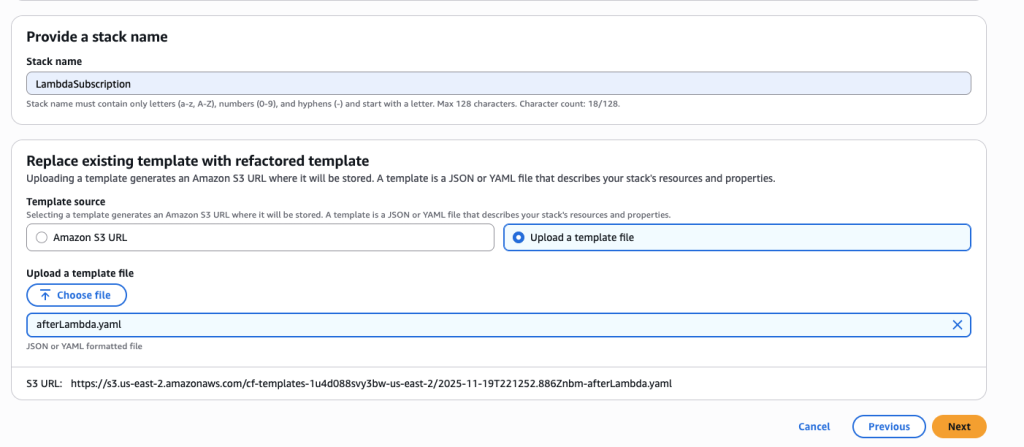
  10. You want to create a new stack to manage the Lambda function and SNS subscription resources. Choose ‘Create a new stack’ and name it ‘LambdaSubscription’.
  11. Upload afterLambda.yaml template file
    Upload afterLambda.yaml template fileIn some scenarios, CloudFormation console can automatically detect logical resource ID renames and pre-fill the mapping for you. The resource mapping is required when there are logical resource ID changes between the original stack and refactored template. Ensure that the mappings are correct before proceeding to the next step.
    In some scenarios, CloudFormation console can automatically detect logical resource ID renames
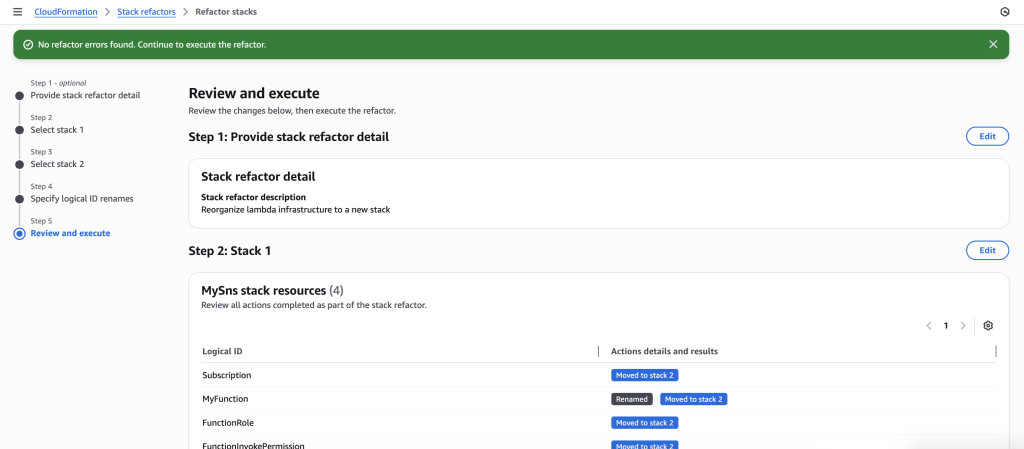
  12. The stack refactor preview will start generating. Wait for the preview to complete. You can verify actions under Stack 1 and Stack 2. It will show you the action for each resource.
    The stack refactor preview will start generating. Wait for the preview to complete. You can verify actions under Stack 1 and Stack 2. It will show you the action for each resource.
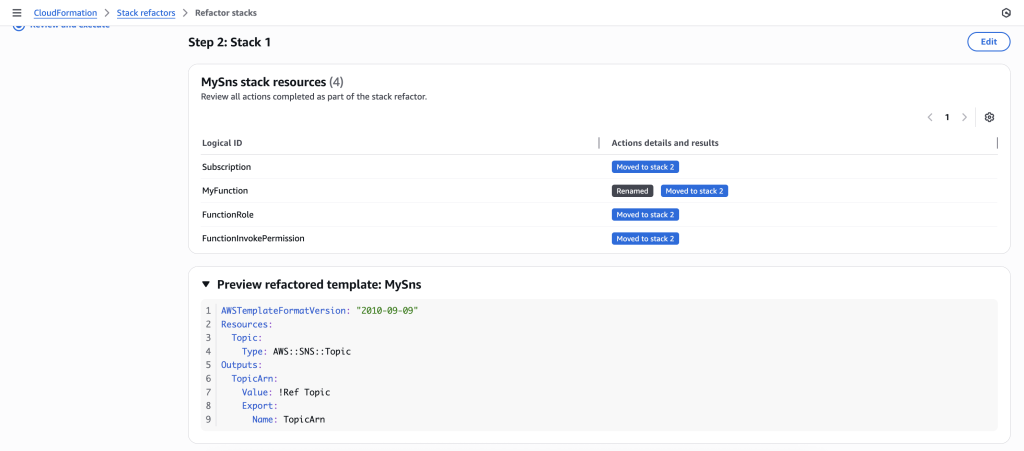
  13. You can also preview the new Stack refactored templates
    You can also preview the new Stack refactored templates
  14. Once you verify the details, go ahead and Execute Refactor. You should be redirected to the stack refactor details.
  15. Once the Stack refactor execution is complete you can view the actions and templates for each of the stacks in your stack refactor.
    Once the Stack refactor execution is complete you can view the actions and templates for each of the stacks in your stack refactor.

Scenario 2: Move resources across multiple stacks.

This scenario demonstrates how to refactor resources across three stacks using the AWS CLI, then review and execute the operation in the CloudFormation console.

  1. Create a new template many-stacks-original.yaml and create a new stack named ‘RefactorManyStacks’ using AWS CLI. This template contains SNS topic (IngestTopic),Lambda function(IngestFunction) and SNS subscription.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      IngestTopic:
        Type: AWS::SNS::Topic
    
      IngestFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt IngestFunctionRole.Arn
          Timeout: 30
    
      IngestSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt IngestFunction.Arn
          Protocol: lambda
          TopicArn: !Ref IngestTopic
    
      IngestFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt IngestFunction.Arn
          SourceArn: !Ref IngestTopic
    
      IngestFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
  2. Create another template many-stacks-original-1.yaml and run the AWS CLI command to create a new stack ‘RefactorManyStacks1’. This template creates another SNS topic (UserTopic), Lambda function (UserFunction) and SNS subscription.
    aws cloudformation create-stack --stack-name RefactorManyStacks --template-body file://many-stacks-original.yaml --capabilities CAPABILITY_IAM
  3. Create a new template many-stacks-original-2.yaml and run the AWS CLI command to create the stack RefactorManyStacks2. This template will also create SNS topic (ConsumerTopic), Lambda function (ConsumerFunction) and SNS subscription to lambda function.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      ConsumerTopic:
        Type: AWS::SNS::Topic
    
      ConsumerFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function-2
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt ConsumerFunctionRole.Arn
          Timeout: 30
    
      ConsumerSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt ConsumerFunction.Arn
          Protocol: lambda
          TopicArn: !Ref ConsumerTopic
    
      ConsumerFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt ConsumerFunction.Arn
          SourceArn: !Ref ConsumerTopic
    
      ConsumerFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function-2"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
    aws cloudformation create-stack --stack-name RefactorManyStacks2 --template-body file://many-stacks-original-2.yaml --capabilities CAPABILITY_IAM

Once all 3 stacks have been created successfully. Create refactored templates.

  1. Create new template many-stacks-refactored.yaml This refactored template only contains SNS topic named IngestTopic and has a new export in it that will export the SNS topic ARN. This export will be used by your other templates to get the required SNS topic ARN.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      IngestTopic:
        Type: AWS::SNS::Topic
    Outputs:
      IngestTopicArn:
        Value: !Ref IngestTopic
        Export:
          Name: IngestTopicArn
  2. Create another template many-stacks-refactored-1.yaml. This template **** has the SNS topic UserTopic and contains the IngestFunction and IngestSubscription and required IAM resources from ‘RefactorManyStacks’. This template switched the !Ref IngestTopic to use the exported valued by using !ImportValue IngestTopicArn. This refactored template also a new export in it that will export the UserTopic ARN.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      UserTopic:
        Type: AWS::SNS::Topic
      IngestFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt IngestFunctionRole.Arn
          Timeout: 30
    
      IngestSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt IngestFunction.Arn
          Protocol: lambda
          TopicArn: !ImportValue IngestTopicArn
    
      IngestFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt IngestFunction.Arn
          SourceArn: !ImportValue IngestTopicArn
    
      IngestFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
    Outputs:
      UserTopicArn:
        Value: !Ref UserTopic
        Export:
          Name: UserTopicArn
  3. Create another template many-stacks-refactored-2.yaml. This template has the Consumer* resources along with Lambda function (UserFunction) and SNS subscription (UserSubscription). The template is using exported value from many-stacks-refactored-1.yaml by using !ImportValue UserTopicArn

    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      ConsumerTopic:
        Type: AWS::SNS::Topic
    
      ConsumerFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function-2
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt ConsumerFunctionRole.Arn
          Timeout: 30
    
      ConsumerSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt ConsumerFunction.Arn
          Protocol: lambda
          TopicArn: !Ref ConsumerTopic
    
      ConsumerFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt ConsumerFunction.Arn
          SourceArn: !Ref ConsumerTopic
    
      ConsumerFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function-2"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
      UserFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function-1
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt UserFunctionRole.Arn
          Timeout: 30
    
      UserSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt UserFunction.Arn
          Protocol: lambda
          TopicArn: !ImportValue UserTopicArn
    
      UserFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt UserFunction.Arn
          SourceArn: !ImportValue UserTopicArn
    
      UserFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function-1"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow


  4. Start the stack refactor using AWS CLI.
    aws cloudformation create-stack-refactor --stack-definitions StackName=RefactorManyStacks,TemplateBody@=file://many-stacks-refactored.yaml StackName=RefactorManyStacks1,TemplateBody@=file://many-stacks-refactored-1.yaml StackName=RefactorManyStacks2,TemplateBody@=file://many-stacks-refactored-2.yaml --description "three stack refactor"
  5. Go to stack CloudFormation console and go to ‘Stack refactor’ homepage, click on the stack refactor you just created.
    Go to stack CloudFormation console and go to ‘Stack refactor’ homepage, click on the stack refactor you just created.
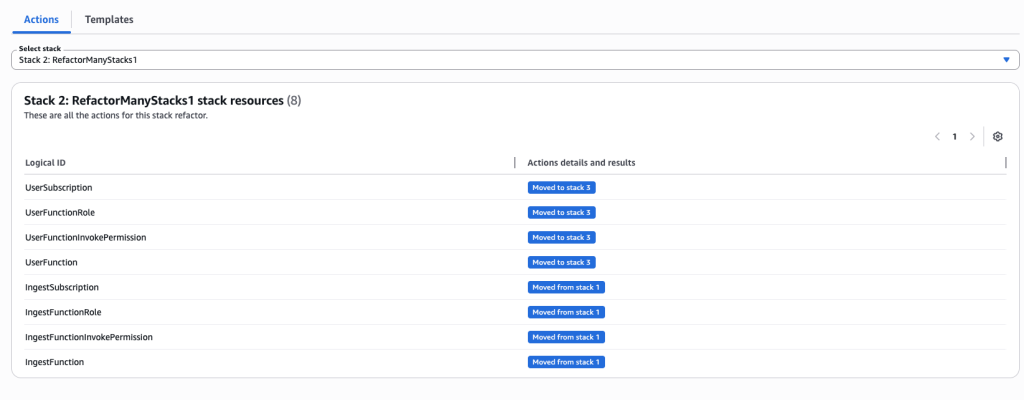
  6. Review actions for each resource and each stack. You can choose individual stacks from drop down.
    Review actions for each resource and each stack. You can choose individual stacks from drop down.
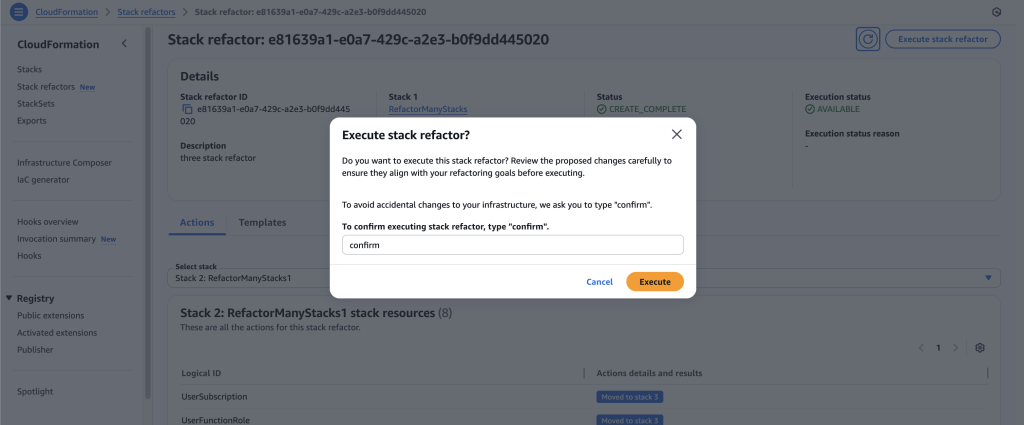
  7. Once you’re ready to execute the stack refactor, click on ‘Execute stack refactor’ and input the confirmation text.
    Once you’re ready to execute the stack refactor, click on ‘Execute stack refactor’ and input the confirmation text.
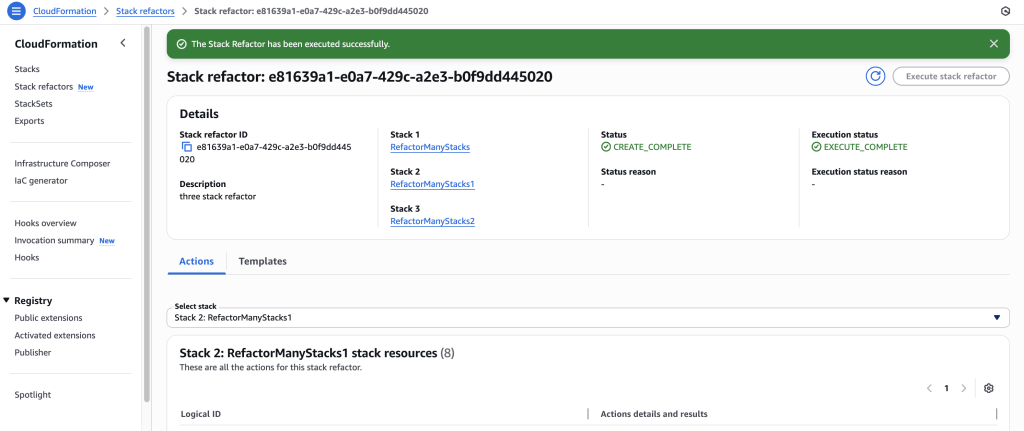
  8. Wait for stack refactor execution to finish.
    Wait for stack refactor execution to finish.
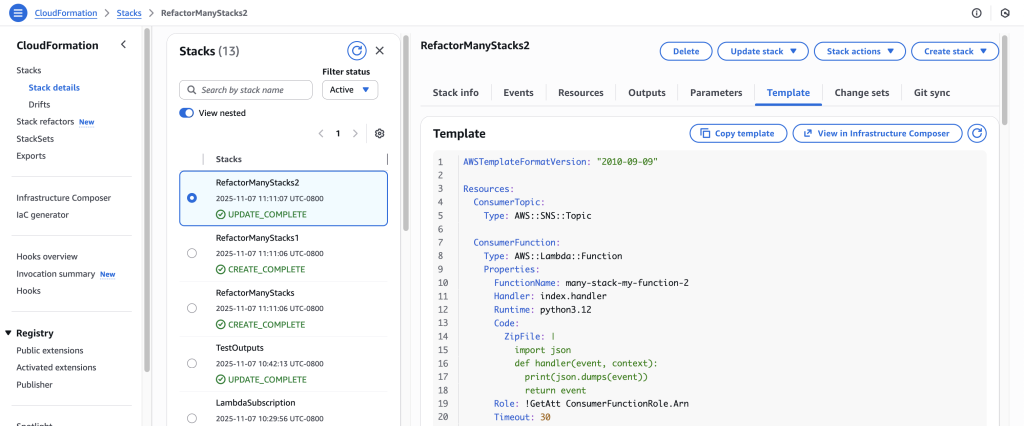
  9. Click on the stack in the details to navigate to the stack details. You can verify the refactor changes here.
    Click on the stack in the details to navigate to the stack details. You can verify the refactor changes here.

Scenario 3: Move stacks between 2 nested child stacks stacks

This scenario demonstrates how to move resources between child stacks in a nested stack architecture. Upload child stack templates toAmazon Simple Storage Service (Amazon S3), create a parent stack that references them, then use Stack Refactoring to move resources (like a security group) from one child stack to another. The key is to work directly with the child stack names (which CloudFormation auto-generates based on parent stack name and logical IDs) rather than the parent stack itself. After refactoring, update the parent stack to reference the new child template versions in S3.

This approach lets you reorganize nested stack architectures while maintaining the parent-child relationship structure.

  1. Create first child stack template vpc.yaml. This template creates a new Virtual Private Cloud(VPC). Upload this new template file to S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'VPC Stack - Contains only VPC'
    
    Resources:
      MyVPC:
        Type: AWS::EC2::VPC
        Properties:
          CidrBlock: 10.0.0.0/16
    
    Outputs:
      VPCId:
        Value: !Ref MyVPC
  2. Create second child stack template resource.yaml . This template will create S3 bucket and EC2 Security Group. Once you create this template file, upload it to an S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: ' Contains security group and S3 bucket'
    
    Resources:
      MySecurityGroup:
        Type: AWS::EC2::SecurityGroup
        Properties:
          GroupDescription: Security group for testing
          SecurityGroupIngress:
            - IpProtocol: tcp
              FromPort: 80
              ToPort: 80
              CidrIp: 0.0.0.0/0
    
      MyS3Bucket:
        Type: AWS::S3::Bucket
    
    Outputs:
      SecurityGroupId:
        Value: !Ref MySecurityGroup
      S3BucketName:
        Value: !Ref MyS3Bucket
  3. Create parent stack template file parent.yaml. Make sure to edit the TemplateURL with your S3 Object URL

    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'Parent stack for test'
    
    Resources:
      VPCStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/vpc.yaml
    
      ResourceStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/resource.yaml
    
    Outputs:
      VPCStackName:
        Value: !Ref VPCStack
      ResourceStackName:
        Value: !Ref ResourceStack


  4. Create this new Parent stack using AWS CLI :
    aws cloudformation create-stack --stack-name ParentStack --template-body file://parent.yaml --capabilities CAPABILITY_IAM
  5. We will use stack refactor to move EC2 Security group from ResourceStack to VPCStack.
  6. Create new template file VPCStackAfter.yaml. This template now has VPC and EC2 Security group resources. Upload this template to S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: ' VPC Stack AFTER - Contains VPC and security group'
    
    Resources:
      MyVPC:
        Type: AWS::EC2::VPC
        Properties:
          CidrBlock: 10.0.0.0/16
    
      MySecurityGroup:
        Type: AWS::EC2::SecurityGroup
        Properties:
          GroupDescription: Security group for testing
          SecurityGroupIngress:
            - IpProtocol: tcp
              FromPort: 80
              ToPort: 80
              CidrIp: 0.0.0.0/0
    
    Outputs:
      VPCId:
        Value: !Ref MyVPC
      SecurityGroupId:
        Value: !Ref MySecurityGroup
  7. Create ResourceStackAfter.yaml The resource stack will only contain s3 bucket resource. Upload this template to S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'Resource Stack AFTER - Contains only S3 bucket'
    
    Resources:
      MyS3Bucket:
        Type: AWS::S3::Bucket
    
    Outputs:
      S3BucketName:
        Value: !Ref MyS3Bucket
  8. Navigate to CloudFormation Console and select Start stack refactor
  9. Add a description for Stack refactor:
    Add a description for Stack refactor:
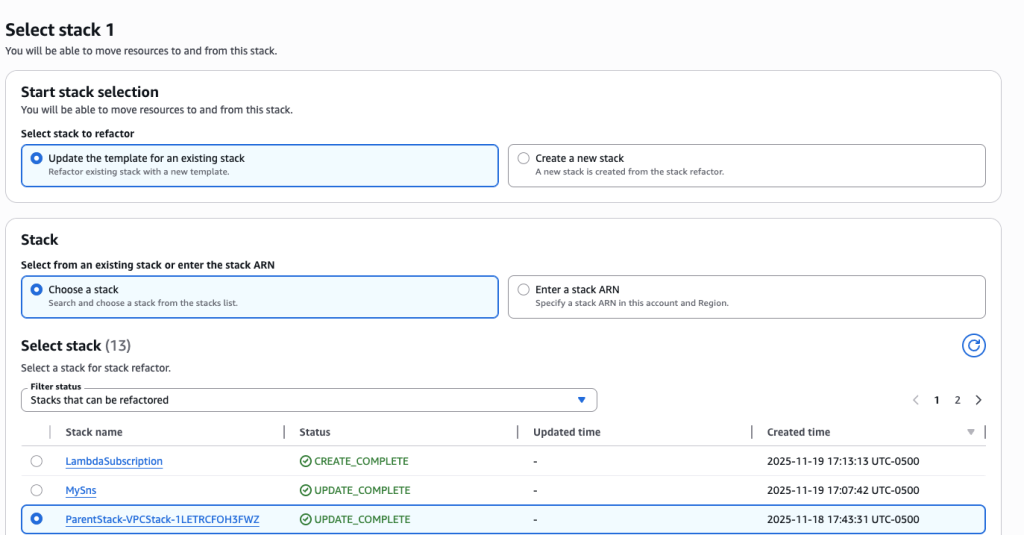
  10. Choose “Update the template for an existing stack” and select child stack “ParentStack-VPCStack-12345”. Make sure to choose the child stack and not the Root/Parent stack.
    Choose “Update the template for an existing stack” and select child stack “ParentStack-VPCStack-12345”. Make sure to choose the child stack and not the Root/Parent stack.
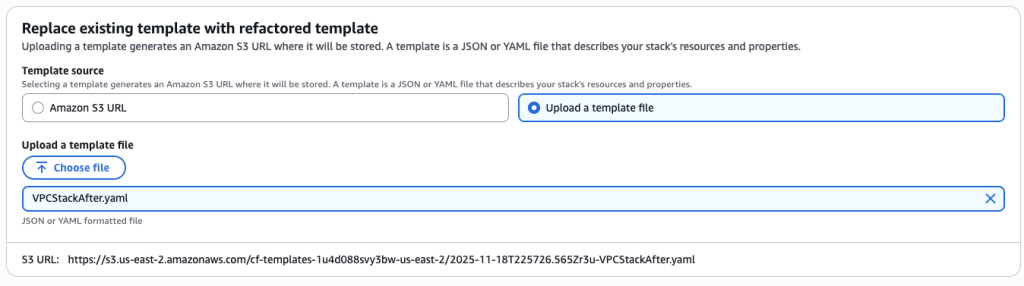
  11. Upload the new template VPCStackAfter.yaml
    Upload the new template VPCStackAfter.yaml
  12. For Stack2, again select ‘Update the template for an existing stack’ and select to 2nd child stack “ParentStack-ResourceStack-12345”
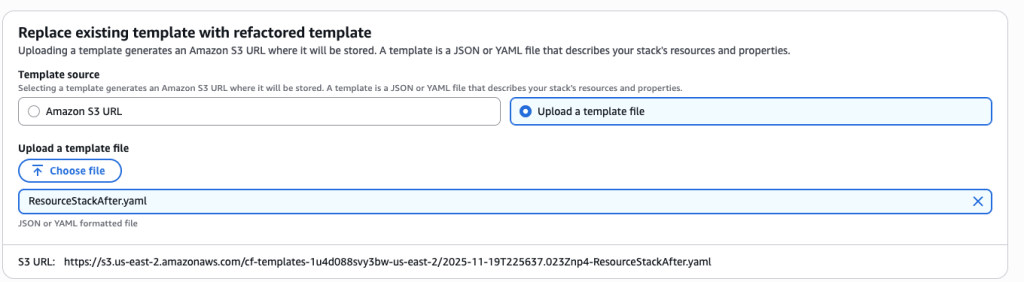
  13. Upload the template ResourceStackAfter.yaml
    Upload the template ResourceStackAfter.yaml
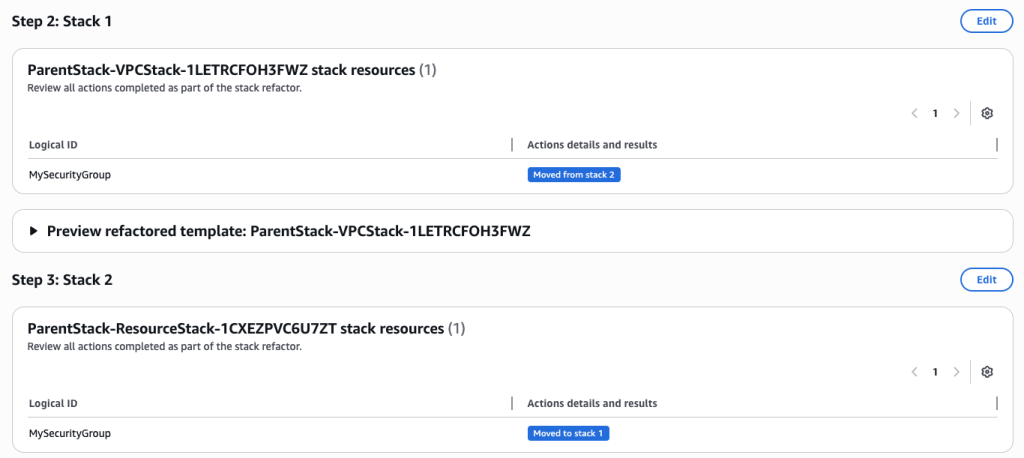
  14. Review the Stack refactor. Once you have verified all the actions and details choose ‘Execute Refactor’
    Review the Stack refactor. Once you have verified all the actions and details choose ‘Execute Refactor
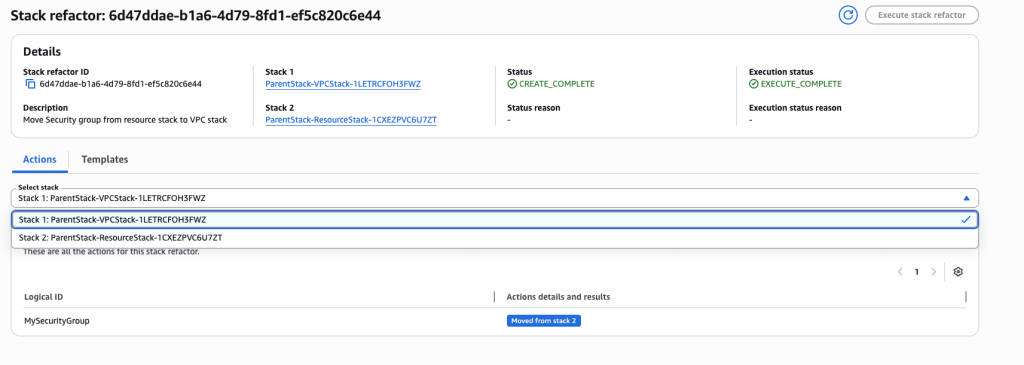
  15. You can verify the refactor templates.
    stack Console
  16. Lastly, update your ParentStack.yaml to reference the new child template versions in S3 bucket.
    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'Parent stack for test'
    
    Resources:
      VPCStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/VPCStackAfter.yaml
    
      ResourceStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/ResourceStackAfter.yaml
    
    Outputs:
      VPCStackName:
        Value: !Ref VPCStack
      ResourceStackName:
        Value: !Ref ResourceStack

Best Practices

Stack Refactoring offers powerful flexibility, but a few strategic considerations will help ensure smooth operations. Test your refactoring plans in non-production environments first, particularly when working with complex dependency chains or resources that have strict ordering requirements. The preview phase becomes your primary safety mechanism—treat it as a thorough code review, examining each planned action before execution. When moving resources between stacks, pay close attention to cross-stack references. Converting direct references to export/import patterns maintains loose coupling and prevents circular dependencies. CloudFormation will automatically manage these conversions during refactoring, but understanding the resulting architecture helps you avoid introducing fragility into your infrastructure.

For scenarios where you’re emptying a source stack entirely, remember that CloudFormation requires at least one resource per stack. This makes placeholder resources like AWS::CloudFormation::WaitConditionHandle a useful temporary measure—they consume no actual AWS resources and can be safely deleted along with the stack once the refactoring completes.

Document your refactoring decisions alongside the templates themselves. Future maintainers (including yourself in six months) will appreciate understanding why resources were organized in particular ways. Include comments in your templates explaining the reasoning behind stack boundaries and resource groupings.

Consider the operational impact of your refactoring. While resources themselves remain stable, monitoring dashboards, automation scripts, or other tooling that references stack names or logical IDs may need updates. Plan these ancillary changes as part of your refactoring workflow rather than discovering them afterward.

Finally, leverage refactoring as an opportunity to improve template quality more broadly. If you’re already reorganizing resources, consider also updating documentation, standardizing naming conventions, or adding tags for better resource management.

Conclusion

CloudFormation Stack Refactoring transforms how you organize and maintain infrastructure as code, enabling stack architecture to evolve alongside applications and organizational needs. This capability provides the flexibility to restructure without the risk and complexity of traditional resource recreation approaches. Whether you’re breaking apart monolithic stacks, consolidating fragmented infrastructure, or simply renaming resources to match current conventions, Stack Refactoring lets you adapt CloudFormation organization to changing requirements without operational disruption.

To get started, visit the CloudFormation console or explore the AWS CloudFormation API reference for programmatic access patterns. Stack Refactoring is available today in all commercial AWS regions.

Brian Terry

Brian Terry

Brian Terry, Senior WW Data & AI PSA, is an innovation leader with 20+ years of experience in technology and engineering. Pursuing a Ph.D. in Computer Science at the University of North Dakota. Brian has spearheaded generative AI projects, optimized infrastructure scalability, and driven partner integration strategies. He is passionate about leveraging technology to deliver scalable, resilient solutions that foster business growth and innovation

Idriss Louali Abdou

Idriss Laouali Abdou

Idriss Laouali Abdou is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through AWS CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Sanchi Halikar

Sanchi Halikar

Sanchi is a Solutions Architect supporting Enterprise customers at AWS. She helps customers design and implement cloud solutions with a focus on DevOps strategies. She specializes in Infrastructure as Code and is passionate about leveraging generative AI in software development

Jamie, AWS IaC console Front-end engineer

Jamie To

Jamie is a Front End Engineer and has been delivering console features to AWS IaC customers for the last 3 years. Outside of work, Jamie enjoys drawing and playing foosball.

Take fine-grained control of your AWS CloudFormation StackSets Deployment with StackSet Dependencies

Post Syndicated from Tanvi Ravindra Malali original https://aws.amazon.com/blogs/devops/take-fine-grained-control-of-your-aws-cloudformation-stacksets-deployment-with-stackset-dependencies/

Introduction

AWS CloudFormation StackSets enable you to deploy CloudFormation stacks across multiple AWS accounts and regions with a single operation, providing centralized management of infrastructure at scale through AWS Organizations integration. In enterprise environments, multiple StackSet often need to deploy in a specific order. For example, networking infrastructure must be ready before applications can deploy successfully.

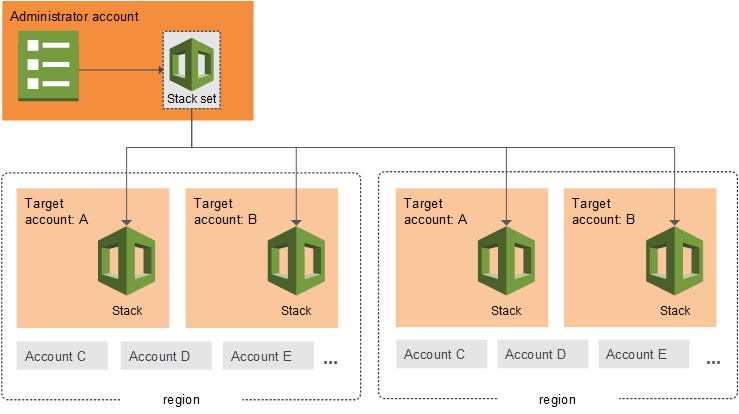
Architecture diagram showing an Administrator account with a Stack set, and many target accounts with their own stacks, which in turn control other stacks. Demonstrating how a multi account, multi stack architecture can get complicated.

Figure 1: Example of a multi-region AWS CloudFormation StackSet architecture with an administrative account and target accounts

Previously, when multiple StackSets had auto-deployment enabled, they operated independently without coordination. This could cause deployment failures when dependent infrastructure wasn’t ready, forcing customers to implement complex workarounds or disable auto-deployment entirely.

We are announcing StackSets dependencies, a new feature that gives you fine-grained control over the deployment order of your auto-deployed StackSets, elegantly solving these orchestration challenges.

Feature Overview

This new feature introduces the ability to define dependencies between StackSets using the new DependsOn parameter in the AutoDeployment configuration. When accounts move between Organizational Units or are added to your organization, StackSets automatically orchestrates deployments according to your defined sequence, ensuring foundational infrastructure deploys before dependent applications.

Key capabilities include:

  • Dependency Management: Define up to 10 dependencies per StackSet, with up to 100 dependencies per account. For example, if you have 5 StackSets with 5 dependencies each, you have 25 dependencies counting towards the 100 dependency limit. You can request a limit increase through the service quota console.
  • Cycle Detection: Built-in validation prevents circular dependencies with error messages.
  • Cross-Region Support: Dependencies work across regions.
  • Automatic Cleanup: Dependencies are removed when StackSets are deleted or Organizations are deactivated.

How it works

Let’s walk through this feature with a practical example. Consider an infrastructure setup where you have: A central Infrastructure StackSet that creates IAM roles and networking components and multiple Application StackSets that depend on these foundational resources.

With StackSets dependencies, you can make sure the Infrastructure StackSet completes deployment before any Application StackSets begin, preventing deployment failures due to missing dependencies.

Implementation Scenarios

Let’s explore three common scenarios where StackSets Dependencies provides value:

Scenario 1: Foundation-First Deployment

Use Case: You have a foundational Infrastructure StackSet that creates IAM roles and networking components, and multiple Application StackSets that depend on these resources.

Setup:

  • Infrastructure StackSet ARNs (creates IAM roles, VPCs, security groups)
  • App1 StackSet (web application requiring IAM roles)
  • App2 StackSet (API service requiring networking components)
  • No additional permissions are required to use this feature.

Console Experience

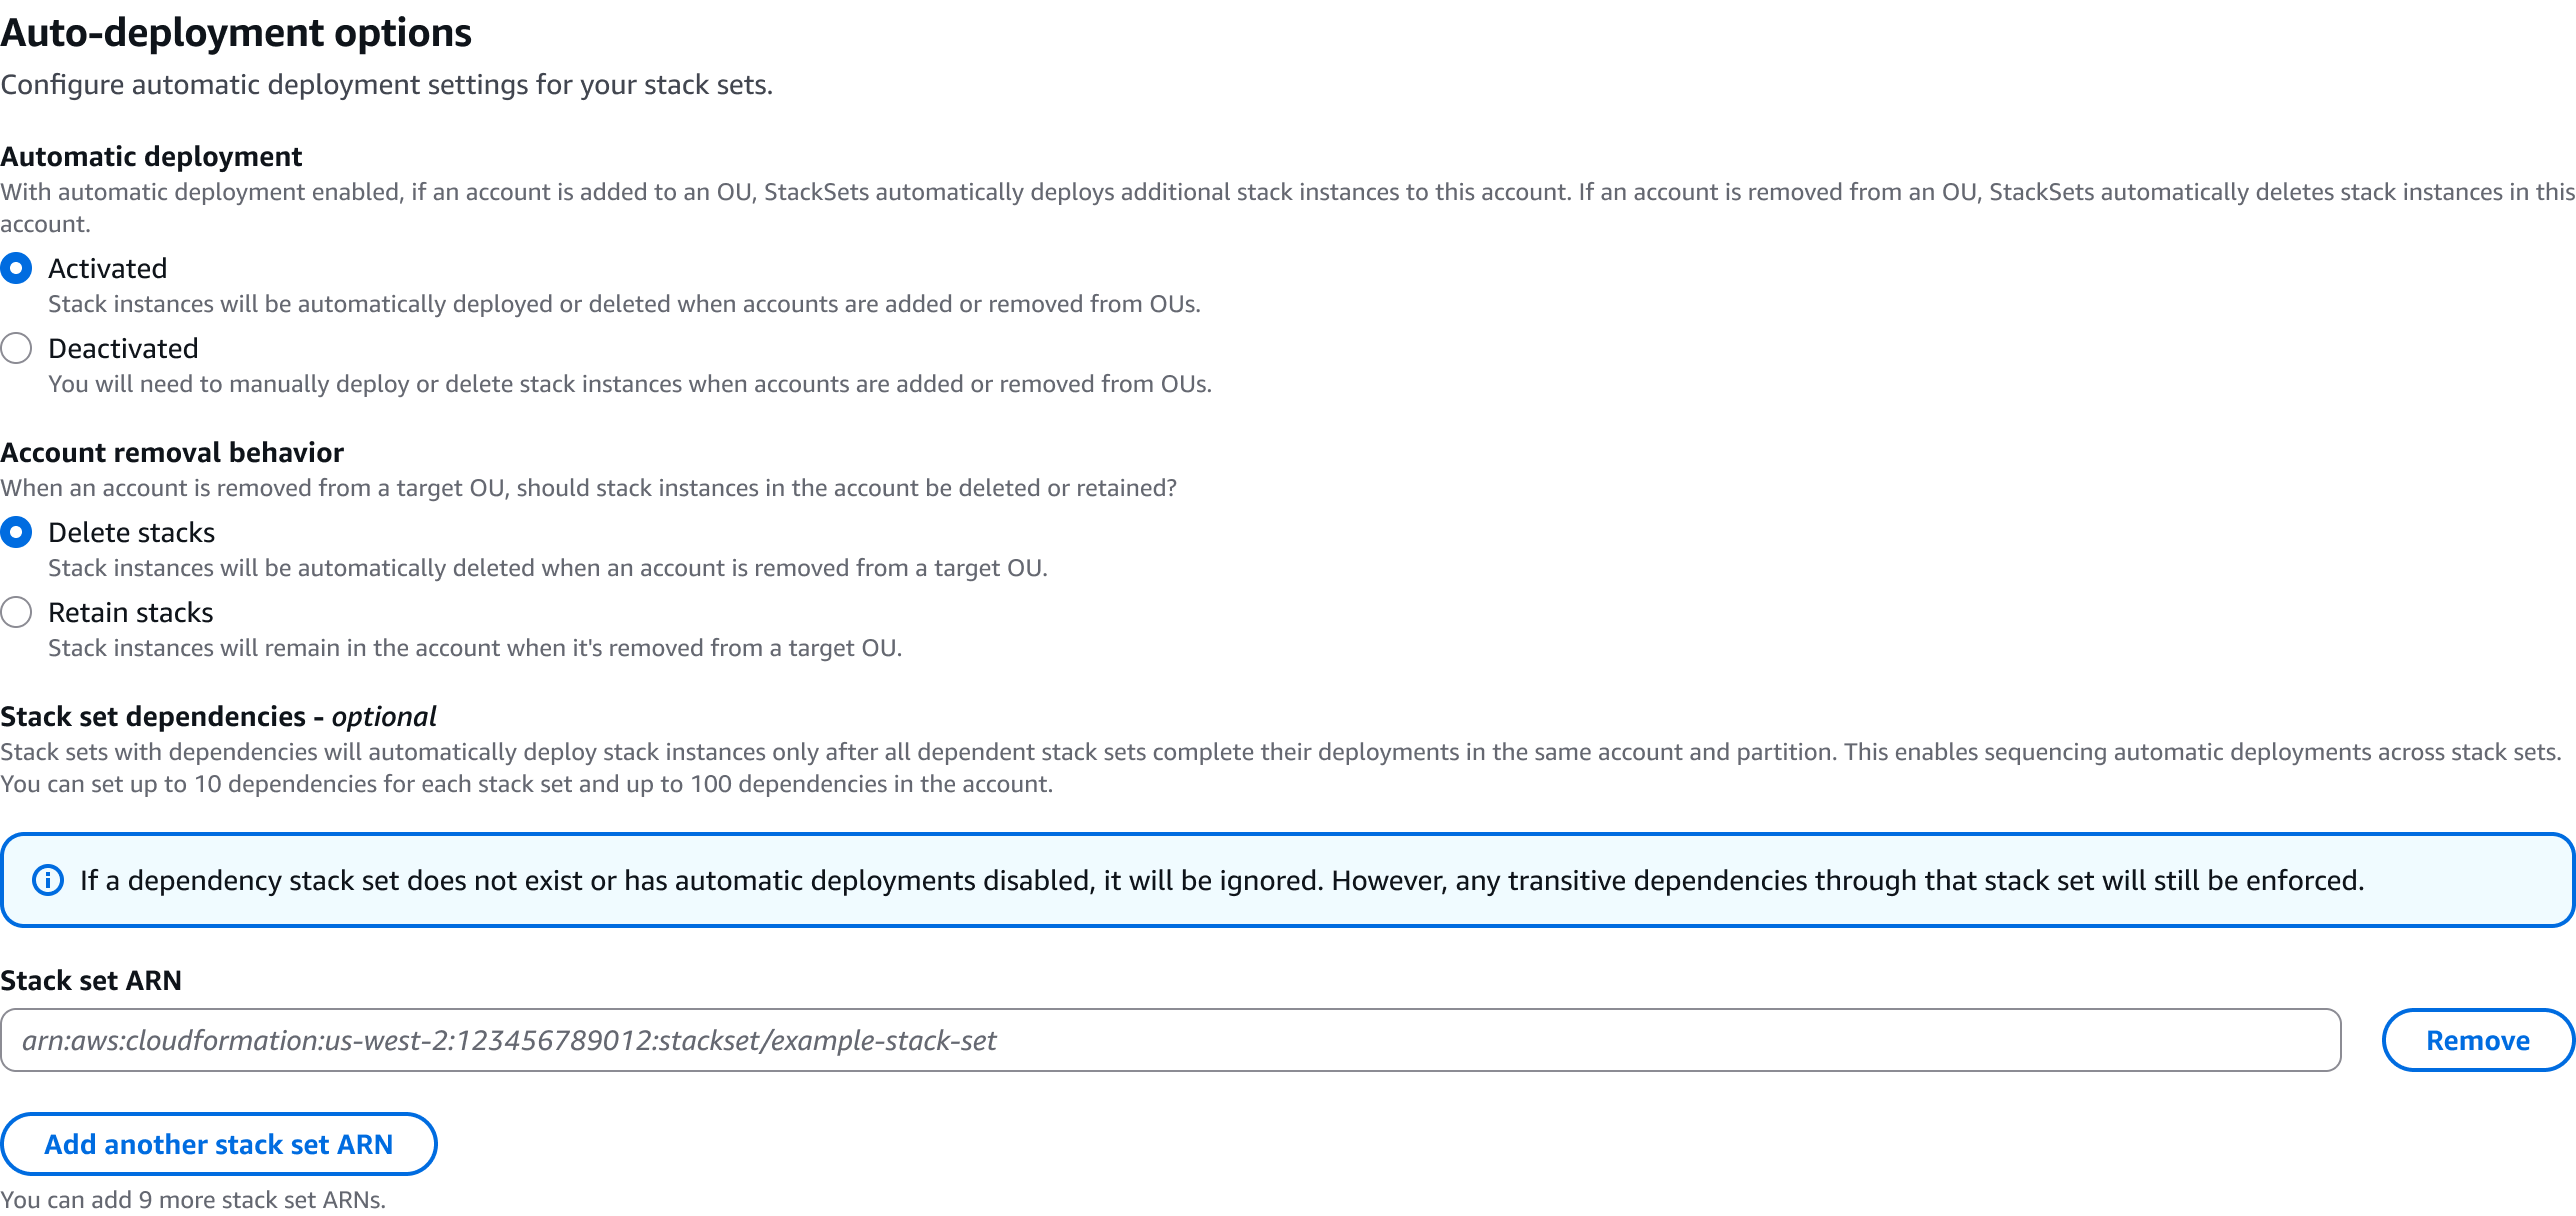
The CloudFormation console provides an intuitive interface for managing StackSet dependencies. Log into the AWS console with your credentials, with an IAM user or administrative user, according to your access. Navigate to the Cloudformation service and create a new Stack or add a YAML/JSON template, where you will be configuring dependencies. In the Step 4 of the Create StackSet wizard, you’ll find a new “StackSet dependencies” form field in the Auto-deployment options section. You can use the attribute editor to add StackSet ARNs for dependencies. The console includes input validation for ARN format and helpful alerts about dependency behavior.

Console view showing options to Activate or Deactivate Automatic deployment, and whether to Delete or Retain stacks, and the new feature, Stack set dependencies, and a space to designate a dependent stack set.

Figure 2: CloudFormation StackSets Console – Auto-deployment options view

AWS CLI Implementation:

  1. Create the foundational Infrastructure StackSet:

aws cloudformation create-stack-set \
  --stack-set-name Infrastructure \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --template-body file://infrastructure-template.yaml \
  --region us-east-1

2. Create App1 with dependency on Infrastructure:

aws cloudformation create-stack-set \
  --stack-set-name App1 \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,\
  DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/Infrastructure:uuid \
  --template-body file://app1-template.yaml \
  --region us-east-1

3. Create App2 with dependency on Infrastructure:

aws cloudformation create-stack-set \
  --stack-set-name App2 \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/Infrastructure:uuid \
  --template-body file://app2-template.yaml \
  --region us-west-2

Now, when accounts are added to your organization, Infrastructure deploys first, then App1 and App2 deploy in parallel after Infrastructure completes.

Scenario 2: Multi-Dependency Application

Use Case: Your application requires both networking and security components to be ready before deployment.

Setup:

  • Networking StackSet (VPCs, subnets, route tables)
  • Security StackSet (security groups, NACLs, IAM policies)
  • Application StackSet (requires both networking and security)

Implementation:

  1. Create Networking StackSet

aws cloudformation create-stack-set \
  --stack-set-name Networking \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --template-body file://networking-template.yaml \
  --region us-east-1

2. Create Security StackSet

aws cloudformation create-stack-set \
  --stack-set-name Security \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --template-body file://security-template.yaml \
  --region us-east-1

3. Create Application with dependencies on both Networking and Security

aws cloudformation create-stack-set \
  --stack-set-name Application \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/Networking:uuid,arn:aws:cloudformation:us-east-1:123456789012:Stackset/Security:uuid \
  --template-body file://application-template.yaml \
  --region us-east-1

As a result, Networking and Security StackSets deploy in parallel, and Application waits for both to complete before starting.

Scenario 3: Resolving Dependency Conflicts

Use Case: You need to update existing StackSets to fix incorrect dependency relationships.

Problem: You have App1 and App2 StackSets. There is an existing dependency that App2 has on App1, but you realize App1 should depend on App2, not the other way around.

Implementation:

First, try to set App1 to depend on App2 (this will fail due to cycle):

aws cloudformation update-stack-set \
  --stack-set-name App1 \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/App2:uuid \
  --use-previous-template

This action will result in error: “Detected cycle(s) between auto-deployment dependencies”. If dependency validation cannot be completed, you’ll receive appropriate error messages to help troubleshoot configuration issues.

Now let’s remove the existing dependency from App2:

aws cloudformation update-stack-set \
  --stack-set-name App2 \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --use-previous-template

Now successfully set App1 to depend on App2:

aws cloudformation update-stack-set \
  --stack-set-name App1 \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/App2:uuid \
  --use-previous-template

This scenario demonstrates cycle detection and how to resolve dependency conflicts.

Getting Started

StackSet dependencies is available now in all AWS Regions where CloudFormation StackSets are supported. To get started:

  1. Identify Dependencies: Determine which StackSets should deploy first in your infrastructure.
  2. Configure Relationships: Use the CloudFormation console or AWS CLI to set up dependencies using StackSet ARNs.
  3. Test Your Sequence: Validate your dependency configuration in a test environment.
  4. Monitor Deployments: Use CloudFormation events to track sequenced deployments.

Log into your account in the console and visit the AWS CloudFormation StackSets console or use the AWS CLI/SDK with AWS credentials configured to start controlling StackSet dependencies today.

Authors


Tanvi Ravindra Malali

Tanvi Ravindra Malali is an Associate Delivery Consultant in the AWS A2C team in ProServe. She is based in New York City. She handles customer projects and codebases, specializing in AI/ML, Data Engineering and Infrastructure as Code. Outside of work, she loves to paint landscapes, DJing her favorite songs, and dances Tango.

Idriss Louali Abdou
Idriss Laouali Abdou

Idriss Laouali Abdou is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

More on Rewiring Democracy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/71226.html

It’s been a month since Rewiring Democracy: How AI Will Transform Our Politics, Government, and Citizenship was published. From what we know, sales are good.

Some of the book’s forty-three chapters are available online: chapters 2, 12, 28, 34, 38, and 41.

We need more reviews—six on Amazon is not enough, and no one has yet posted a viral TikTok review. One review was published in Nature and another on the RSA Conference website, but more would be better. If you’ve read the book, please leave a review somewhere.

My coauthor and I have been doing all sort of book events, both online and in person. This book event, with Danielle Allen at the Harvard Kennedy School Ash Center, is particularly good. We also have been doing a ton of podcasts, both separately and together. They’re all on the book’s homepage.

There are two live book events in December. If you’re in Boston, come see us at the MIT Museum on 12/1. If you’re in Toronto, you can see me at the Munk School at the University of Toronto on 12/2.

I’m also doing a live AMA on the book on the RSA Conference website on 12/16. Register here.

AI as Cyberattacker

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/ai-as-cyberattacker.html

From Anthropic:

In mid-September 2025, we detected suspicious activity that later investigation determined to be a highly sophisticated espionage campaign. The attackers used AI’s “agentic” capabilities to an unprecedented degree­—using AI not just as an advisor, but to execute the cyberattacks themselves.

The threat actor—­whom we assess with high confidence was a Chinese state-sponsored group—­manipulated our Claude Code tool into attempting infiltration into roughly thirty global targets and succeeded in a small number of cases. The operation targeted large tech companies, financial institutions, chemical manufacturing companies, and government agencies. We believe this is the first documented case of a large-scale cyberattack executed without substantial human intervention.

[…]

The attack relied on several features of AI models that did not exist, or were in much more nascent form, just a year ago:

  1. Intelligence. Models’ general levels of capability have increased to the point that they can follow complex instructions and understand context in ways that make very sophisticated tasks possible. Not only that, but several of their well-developed specific skills—in particular, software coding­—lend themselves to being used in cyberattacks.
  2. Agency. Models can act as agents—­that is, they can run in loops where they take autonomous actions, chain together tasks, and make decisions with only minimal, occasional human input.
  3. Tools. Models have access to a wide array of software tools (often via the open standard Model Context Protocol). They can now search the web, retrieve data, and perform many other actions that were previously the sole domain of human operators. In the case of cyberattacks, the tools might include password crackers, network scanners, and other security-related software.

Scam USPS and E-Z Pass Texts and Websites

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/scam-usps-and-e-z-pass-texts-and-websites.html

Google has filed a complaint in court that details the scam:

In a complaint filed Wednesday, the tech giant accused “a cybercriminal group in China” of selling “phishing for dummies” kits. The kits help unsavvy fraudsters easily “execute a large-scale phishing campaign,” tricking hordes of unsuspecting people into “disclosing sensitive information like passwords, credit card numbers, or banking information, often by impersonating well-known brands, government agencies, or even people the victim knows.”

These branded “Lighthouse” kits offer two versions of software, depending on whether bad actors want to launch SMS and e-commerce scams. “Members may subscribe to weekly, monthly, seasonal, annual, or permanent licenses,” Google alleged. Kits include “hundreds of templates for fake websites, domain set-up tools for those fake websites, and other features designed to dupe victims into believing they are entering sensitive information on a legitimate website.”

Google’s filing said the scams often begin with a text claiming that a toll fee is overdue or a small fee must be paid to redeliver a package. Other times they appear as ads—­sometimes even Google ads, until Google detected and suspended accounts—­luring victims by mimicking popular brands. Anyone who clicks will be redirected to a website to input sensitive information; the sites often claim to accept payments from trusted wallets like Google Pay.

Legal Restrictions on Vulnerability Disclosure

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/legal-restrictions-on-vulnerability-disclosure.html

Kendra Albert gave an excellent talk at USENIX Security this year, pointing out that the legal agreements surrounding vulnerability disclosure muzzle researchers while allowing companies to not fix the vulnerabilities—exactly the opposite of what the responsible disclosure movement of the early 2000s was supposed to prevent. This is the talk.

Thirty years ago, a debate raged over whether vulnerability disclosure was good for computer security. On one side, full disclosure advocates argued that software bugs weren’t getting fixed and wouldn’t get fixed if companies that made insecure software wasn’t called out publicly. On the other side, companies argued that full disclosure led to exploitation of unpatched vulnerabilities, especially if they were hard to fix. After blog posts, public debates, and countless mailing list flame wars, there emerged a compromise solution: coordinated vulnerability disclosure, where vulnerabilities were disclosed after a period of confidentiality where vendors can attempt to fix things. Although full disclosure fell out of fashion, disclosure won and security through obscurity lost. We’ve lived happily ever after since.

Or have we? The move towards paid bug bounties and the rise of platforms that manage bug bounty programs for security teams has changed the reality of disclosure significantly. In certain cases, these programs require agreement to contractual restrictions. Under the status quo, that means that software companies sometimes funnel vulnerabilities into bug bounty management platforms and then condition submission on confidentiality agreements that can prohibit researchers from ever sharing their findings.

In this talk, I’ll explain how confidentiality requirements for managed bug bounty programs restrict the ability of those who attempt to report vulnerabilities to share their findings publicly, compromising the bargain at the center of the CVD process. I’ll discuss what contract law can tell us about how and when these restrictions are enforceable, and more importantly, when they aren’t, providing advice to hackers around how to understand their legal rights when submitting. Finally, I’ll call upon platforms and companies to adapt their practices to be more in line with the original bargain of coordinated vulnerability disclosure, including by banning agreements that require non-disclosure.

And this is me from 2007, talking about “responsible disclosure”:

This was a good idea—and these days it’s normal procedure—but one that was possible only because full disclosure was the norm. And it remains a good idea only as long as full disclosure is the threat.

Holiday Gift Guide 2025

Post Syndicated from Yev original https://www.backblaze.com/blog/holiday-gift-guide-2025/

An illustration of a gift box.

It’s that time of year again where the holidays are barreling towards us at an incredible rate. With so many cyber sales and new things hitting the market, it’s the most wonderful time of year to read gift guides. To help, I’ve asked my fine companions at Backblaze to list out some of their favorite gift ideas for this year, and I’ve compiled them for you here. Enjoy the suggestions, and my rambling commentary!

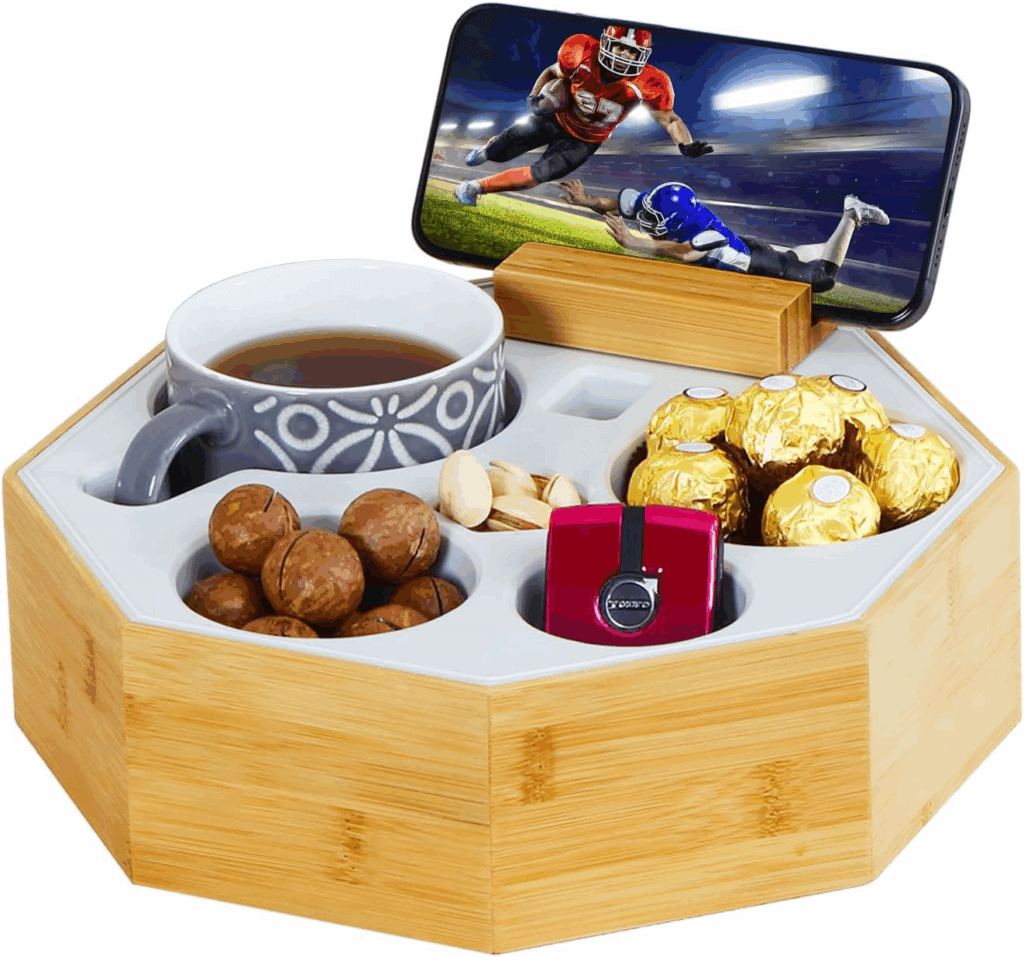
Couch Cady

The couch outside of my office and the recliner are where I spend the majority of my at-home time. What better way to keep your drinks, snacks, and second screens handy than this caddy?

Cereal Cup

Have you ever put cereal and milk into a yeti mug and drank it after everything’s turned into a sugary mush? Me neither, but now you don’t have to—this cup allows you to maintain two great tastes that taste great together, but without them having to touch until you’re ready!

Slow Cooker Seasoning Blends

For the chef in your life—or for the aspiring chef that never quite understood what the word “seasoning” meant—this is a great seasoning blend. Let’s face it, if you’re eating their food, it’s a gift for you too!

Schmidt Brothers Stainless Steel 10-Piece Knife Block Set

Another one for the chef’s in your life. This knife block bundle looks good, by all accounts feels good, and also cuts good—which is great. By the way, does anyone in your life use pairing knives? It’s something I’m just now getting the hang of…fun!

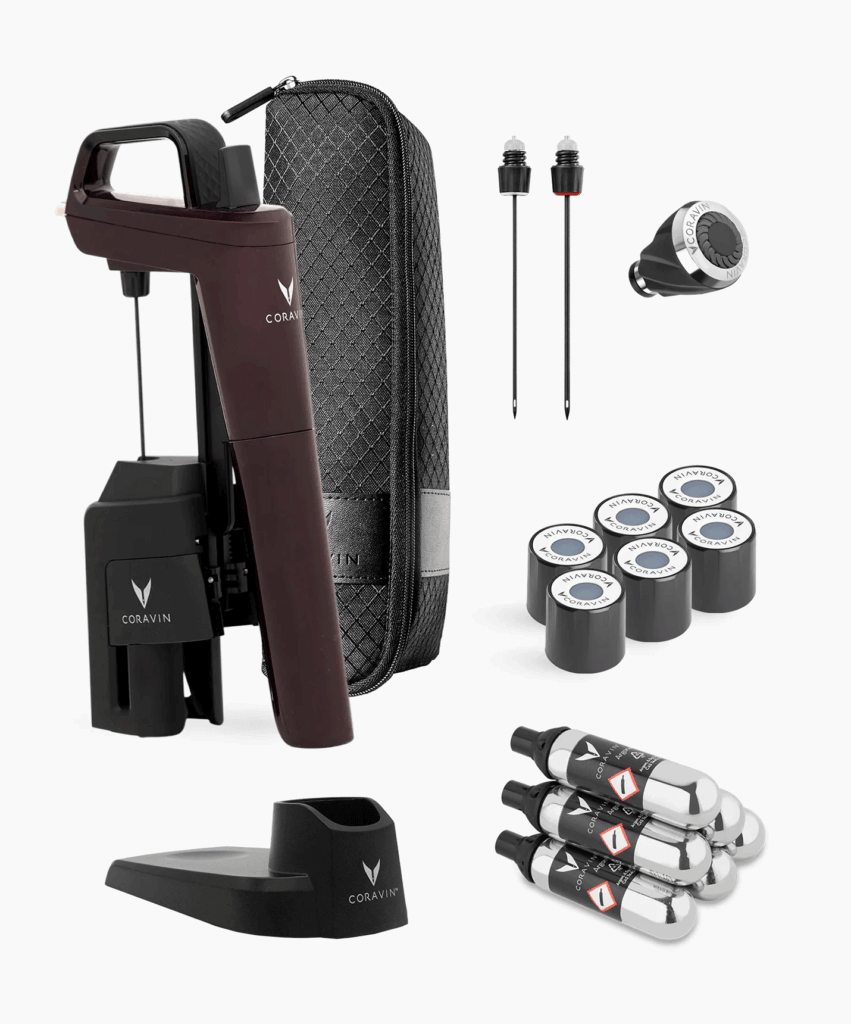
Timeless Six Wine Exploration Bundle

I have this, I use this, and I love this. It’s likely been in gift-guides of yesteryear but it’s just that good. Whether you’re a single human like me who doesn’t want to open a whole bottle and just wants a glass from time to time, or you’re an aficionado wanting to taste his bottles before opening them for a fancy dinner, this pumps inert argon gas into your wine bottles without having to open the cork. Great stuff.

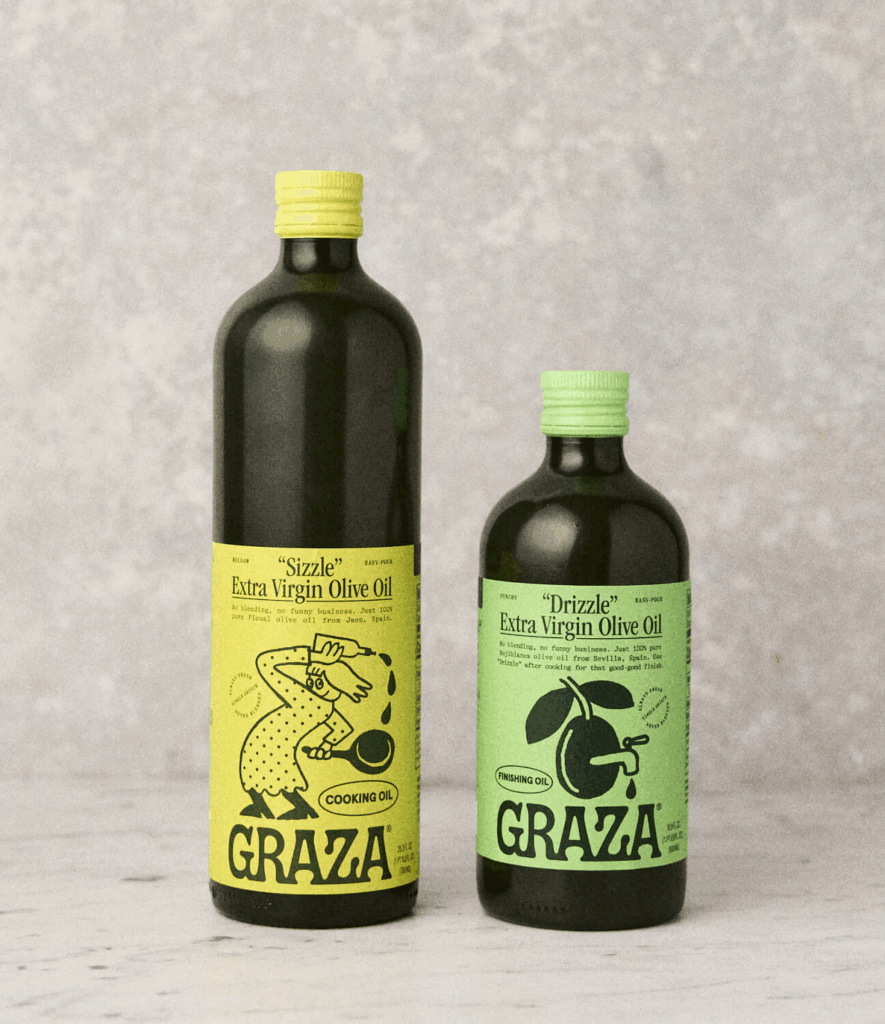
Graze olive oil in glass bottles

Popularized by Tiktok videos, this olive oil stands up to the hype and adds a good amount of actual flavor to your dishes. Whether you’re drizzling or frying, it’s a good recommendation!

Sustainably Raised Meat (for cooks or people who BBQ)

And speaking of frying, Butcherbox allows you to order sustainability sourced meats and have them delivered right to your door. It might be too late if you’re looking for a Thanksgiving bird, but you might need a few steaks eventually!

Terra Kaffe Demi automatic espresso machine

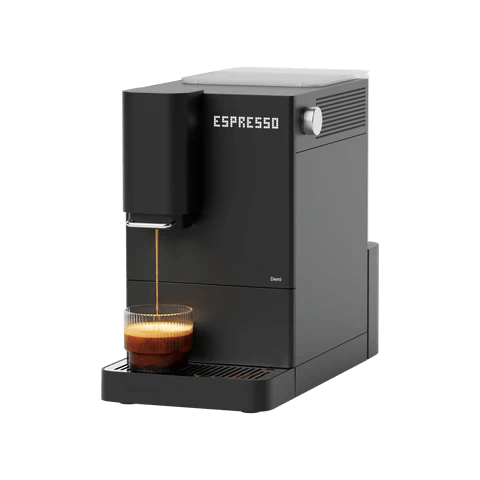
Espresso. Some pronounce it with an “x.” And while it does give you a caffeine boost in a hurry, there’s nothing express about it…except for getting a machine like this that can really speed up and boost your home coffee consumption.

Fancy Onsen Towels

Soft, cuddly, and rapidly drying—these towels are a treat. I got to use one a few months ago while visiting a friend of mine and I still think about them, seriously! It might actually be time to rotate my towels and these are at the top of the list.

Cordless Cleaning and Scrubbing Brush

Cleaning yourself with onsen towels is great, but what about cleaning the actual shower or bath? These allow you to get all the nooks and crannies between the tiles, and because they’re cordless you can also use them on your car rims. Do you ever wash those? You should!

Guardian Kids Bike and Guardian Adult Bike

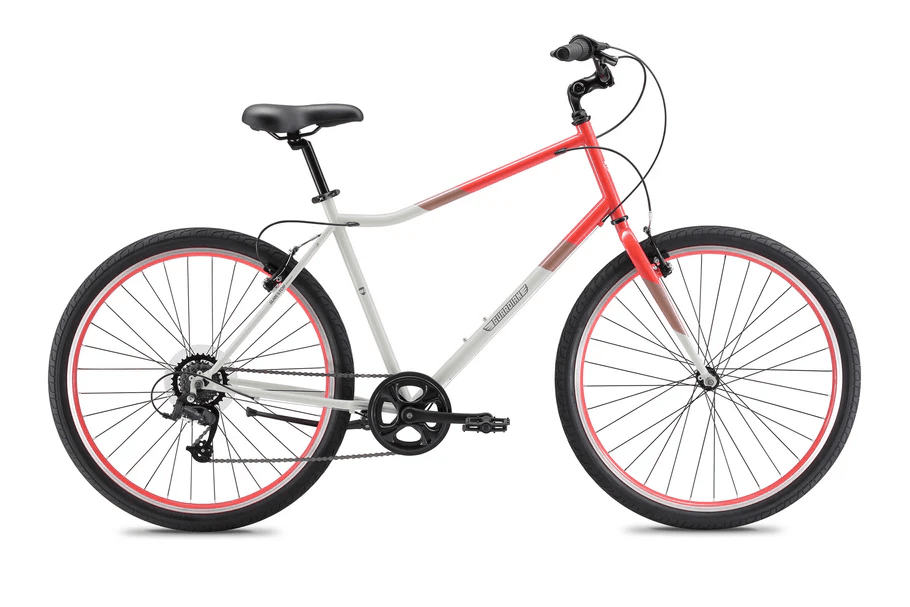
What’s one of my top-10 favorite things? Assembling Ikea furniture while listening to music. But I also enjoy biking! This combines both as the adult and children bikes are shipped to you and you get to assemble them at home before taking them on the road! It keeps costs low, and satisfaction high!

Oura Ring 4

I have been wearing fitness trackers for a very long time, from smartwatches to fitbits to step-counters, and this is my favorite one so far! I love that I can quickly charge it every 4-5 days and it gives me great insights into activity and sleep, without having to wear something bulky to bed.

Patagonia Black Hole Duffel

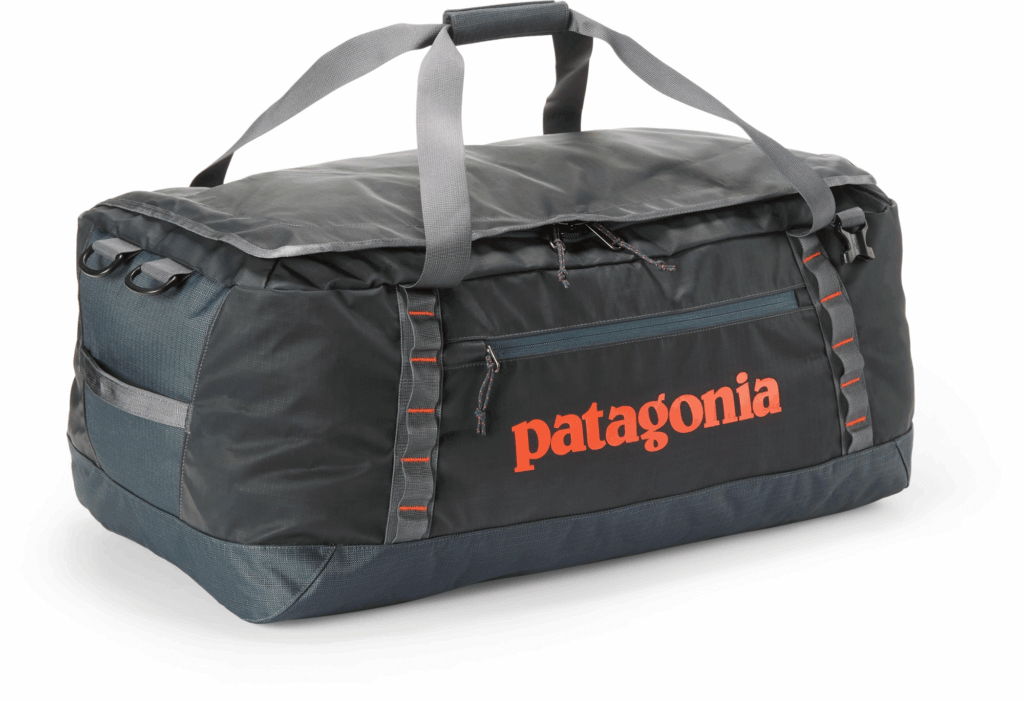
I am often envious of people who travel with duffel bags because of all the stuff you can fit into them. I still use my old-timey rollaboard, but I do have one of these that I throw in the car with me when I hit the ski slopes. These are great, come with backpack straps, and also have a lot of clips where you can hook carabineers up to (which is a great way to bring shoes you don’t want to pack).

Bev Ledge

Airplanes have come a long way but unless you’re sitting in your own personal pod up front (must be nice), there never seems to be enough room for all your stuff! This ledge fits neatly onto your window sill and allows for you to get a little more utility out of your surroundings! Just…don’t get an aisle seat.

Trtl Travel Pillow

As the Wu-Tang Clan once sang, “protect ya neck.” This travel pillow helps do just that when you’re on the go. No one likes falling asleep on a plane and waking up to a stiff neck—this helps!

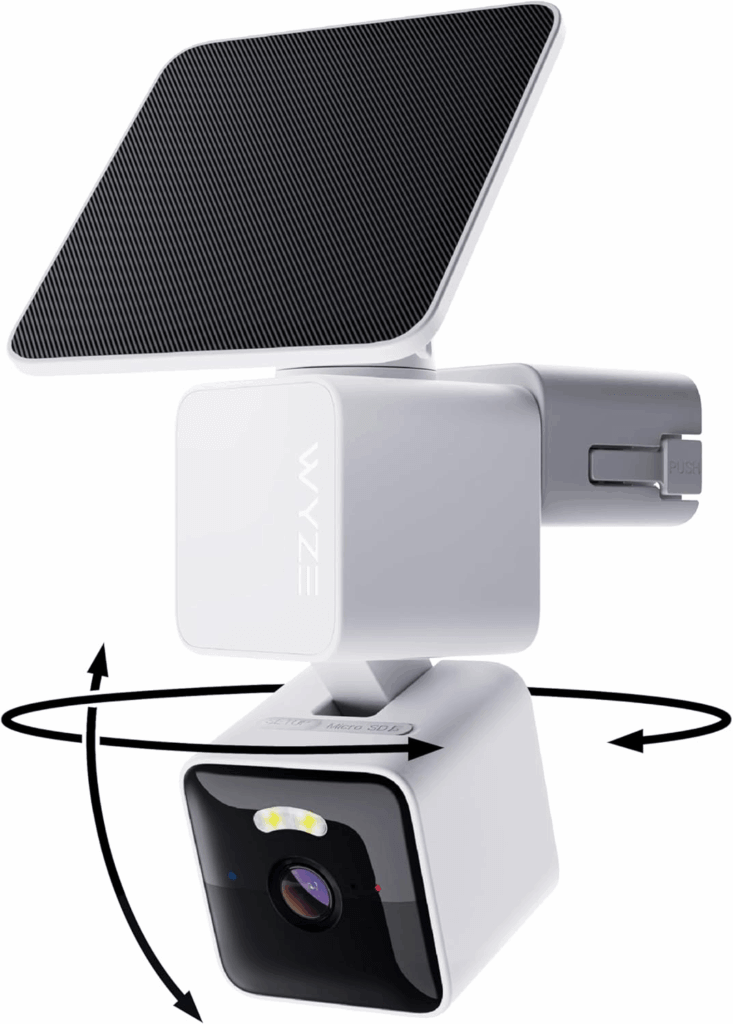
Wyze Solar Cam Pan

These are great for monitoring the outside of your home, but the real killer app comes from using the indoor ones as baby monitors. Seriously, my family has been using them for years in the kiddos’ rooms, and not only is the quality much better than a standard baby monitor, but the recording features make for some really cute videos, and there’s no range restrictions. It’s a win-win-win.

Bambu Lab X1C 3D Printer

3D printing has become very mainstream over the last few years, and this at-home unit with space for multiple filaments makes it incredibly easy to create your favorite designs.

Kindle

Books. You know them, you love them, you should probably read one of my favorites from the last 10 years (The 7 ½ Deaths of Evelyn Hardcastle) and any of the Kindles should help you do just that! I’m a book on tape guy now because I tend to walk a lot (and if you have Audible I highly recommend the Dungeon Crawler Carl series), but if you enjoy holding something in your hands, the paper white Kindles are fantastic.

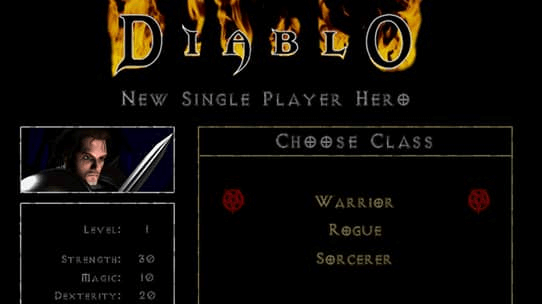
Classic Diablo (or any “good old game” from GOG”)

Classic games are classic for a reason! The recommendation from our org was for Diablo on Good Old Games, but there are a ton of classics there to choose from. One of my favorite series: Quest for Glory. Version 4 my favorite as it dives into Eastern European folktale lore!

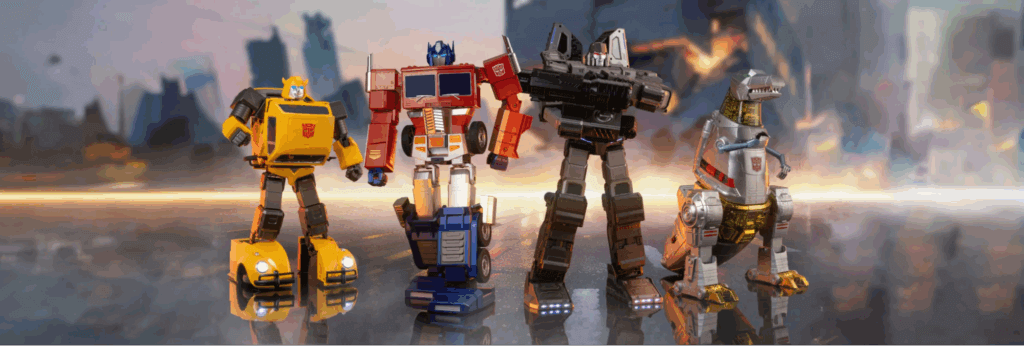
Voice Activated Transformer Robots

Transformers have always been popular, and these voice-activated robots are what I dreamed of when I was a kiddo. Now that I’m no longer a kiddo, I still kind of want one, because watching toys “build themselves” gives me real Toy Story vibes.

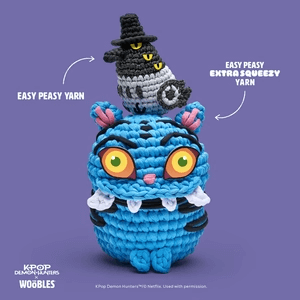
K-pop Demon Hunters Wooble kit

K-Pop Demon Hunters took the world by storm, and now you can turn it into a crafting activity for you or your kiddos! Wobbles are little crochet kits, and come with everything you need to make something cute and squishy, right at home!

Retroid Pocket G2

This little gaming handheld allows you to emulate the games of your youth. Whether you liked playing the Sega Game Gear or the Game Boy, you can get all your favorites in one place with these on-the-go systems.

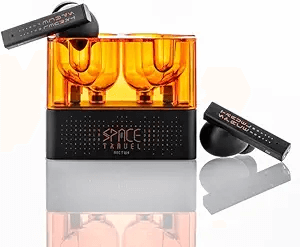
Moondrop Space Travel Headphones

On the go or on the couch, good headphones are paramount. These are relatively shallow and offer noise cancelling technology to keep the outside world out while you’re listening to tunes, audiobooks, or podcasts!

Give the gift of Backblaze

An image of a gift box with the words "Give Backblaze Backup" overlaid

Of course you can always give the gift of Computer Backup. It makes a great gift and helps keep the data of your family and friends safe and sound. Peace of mind is a great gift.

Something you’ve had on your mind didn’t make our list? Tell us in the comments—we love hearing what people are excited about!

The post Holiday Gift Guide 2025 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

AI and Voter Engagement

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/ai-and-voter-engagement.html

Social media has been a familiar, even mundane, part of life for nearly two decades. It can be easy to forget it was not always that way.

In 2008, social media was just emerging into the mainstream. Facebook reached 100 million users that summer. And a singular candidate was integrating social media into his political campaign: Barack Obama. His campaign’s use of social media was so bracingly innovative, so impactful, that it was viewed by journalist David Talbot and others as the strategy that enabled the first term Senator to win the White House.

Over the past few years, a new technology has become mainstream: AI. But still, no candidate has unlocked AI’s potential to revolutionize political campaigns. Americans have three more years to wait before casting their ballots in another Presidential election, but we can look at the 2026 midterms and examples from around the globe for signs of how that breakthrough might occur.

How Obama Did It

Rereading the contemporaneous reflections of the New York Times’ late media critic, David Carr, on Obama’s campaign reminds us of just how new social media felt in 2008. Carr positions it within a now-familiar lineage of revolutionary communications technologies from newspapers to radio to television to the internet.

The Obama campaign and administration demonstrated that social media was different from those earlier communications technologies, including the pre-social internet. Yes, increasing numbers of voters were getting their news from the internet, and content about the then-Senator sometimes made a splash by going viral. But those were still broadcast communications: one voice reaching many. Obama found ways to connect voters to each other.

In describing what social media revolutionized in campaigning, Carr quotes campaign vendor Blue State Digital’s Thomas Gensemer: “People will continue to expect a conversation, a two-way relationship that is a give and take.”

The Obama team made some earnest efforts to realize this vision. His transition team launched change.gov, the website where the campaign collected a “Citizen’s Briefing Book” of public comment. Later, his administration built We the People, an online petitioning platform.

But the lasting legacy of Obama’s 2008 campaign, as political scientists Hahrie Han and Elizabeth McKenna chronicled, was pioneering online “relational organizing.” This technique enlisted individuals as organizers to activate their friends in a self-perpetuating web of relationships.

Perhaps because of the Obama campaign’s close association with the method, relational organizing has been touted repeatedly as the linchpin of Democratic campaigns: in 2020, 2024, and today. But research by non-partisan groups like Turnout Nation and right-aligned groups like the Center for Campaign Innovation has also empirically validated the effectiveness of the technique for inspiring voter turnout within connected groups.

The Facebook of 2008 worked well for relational organizing. It gave users tools to connect and promote ideas to the people they know: college classmates, neighbors, friends from work or church. But the nature of social networking has changed since then.

For the past decade, according to Pew Research, Facebook use has stalled and lagged behind YouTube, while Reddit and TikTok have surged. These platforms are less useful for relational organizing, at least in the traditional sense. YouTube is organized more like broadcast television, where content creators produce content disseminated on their own channels in a largely one-way communication to their fans. Reddit gathers users worldwide in forums (subreddits) organized primarily on topical interest. The endless feed of TikTok’s “For You” page disseminates engaging content with little ideological or social commonality. None of these platforms shares the essential feature of Facebook c. 2008: an organizational structure that emphasizes direct connection to people that users have direct social influence over.

AI and Relational Organizing

Ideas and messages might spread virally through modern social channels, but they are not where you convince your friends to show up at a campaign rally. Today’s platforms are spaces for political hobbyism, where you express your political feelings and see others express theirs.

Relational organizing works when one person’s action inspires others to do this same. That’s inherently a chain of human-to-human connection. If my AI assistant inspires your AI assistant, no human notices and one’s vote changes. But key steps in the human chain can be assisted by AI. Tell your phone’s AI assistant to craft a personal message to one friend—or a hundred—and it can do it.

So if a campaign hits you at the right time with the right message, they might persuade you to task your AI assistant to ask your friends to donate or volunteer. The result can be something more than a form letter; it could be automatically drafted based on the entirety of your email or text correspondence with that friend. It could include references to your discussions of recent events, or past campaigns, or shared personal experiences. It could sound as authentic as if you’d written it from the heart, but scaled to everyone in your address book.

Research suggests that AI can generate and perform written political messaging about as well as humans. AI will surely play a tactical role in the 2026 midterm campaigns, and some candidates may even use it for relational organizing in this way.

(Artificial) Identity Politics

For AI to be truly transformative of politics, it must change the way campaigns work. And we are starting to see that in the US.

The earliest uses of AI in American political campaigns are, to be polite, uninspiring. Candidates viewed them as just another tool to optimize an endless stream of email and text message appeals, to ramp up political vitriol, to harvest data on voters and donors, or merely as a stunt.

Of course, we have seen the rampant production and spread of AI-powered deepfakes and misinformation. This is already impacting the key 2026 Senate races, which are likely to attract hundreds of millions of dollars in financing. Roy Cooper, Democratic candidate for US Senate from North Carolina, and Abdul El-Sayed, Democratic candidate for Senate from Michigan, were both targeted by viral deepfake attacks in recent months. This may reflect a growing trend in Donald Trump’s Republican party in the use of AI-generated imagery to build up GOP candidates and assail the opposition.

And yet, in the global elections of 2024, AI was used more memetically than deceptively. So far, conservative and far right parties seem to have adopted this most aggressively. The ongoing rise of Germany’s far-right populist AfD party has been credited to its use of AI to generate nostalgic and evocative (and, to many, offensive) campaign images, videos, and music and, seemingly as a result, they have dominated TikTok. Because most social platforms’ algorithms are tuned to reward media that generates an emotional response, this counts as a double use of AI: to generate content and to manipulate its distribution.

AI can also be used to generate politically useful, though artificial, identities. These identities can fulfill different roles than humans in campaigning and governance because they have differentiated traits. They can’t be imprisoned for speaking out against the state, can be positioned (legitimately or not) as unsusceptible to bribery, and can be forced to show up when humans will not.

In Venezuela, journalists have turned to AI avatars—artificial newsreaders—to report anonymously on issues that would otherwise elicit government retaliation. Albania recently “appointed” an AI to a ministerial post responsible for procurement, claiming that it would be less vulnerable to bribery than a human. In Virginia, both in 2024 and again this year, candidates have used AI avatars as artificial stand-ins for opponents that refused to debate them.

And yet, none of these examples, whether positive or negative, pursue the promise of the Obama campaign: to make voter engagement a “two-way conversation” on a massive scale.

The closest so far to fulfilling that vision anywhere in the world may be Japan’s new political party, Team Mirai. It started in 2024, when an independent Tokyo gubernatorial candidate, Anno Takahiro, used an AI avatar on YouTube to respond to 8,600 constituent questions over a seventeen-day continuous livestream. He collated hundreds of comments on his campaign manifesto into a revised policy platform. While he didn’t win his race, he shot up to a fifth place finish among a record 56 candidates.

Anno was RECENTLY elected to the upper house of the federal legislature as the founder of a new party with a 100 day plan to bring his vision of a “public listening AI” to the whole country. In the early stages of that plan, they’ve invested their share of Japan’s 32 billion yen in party grants—public subsidies for political parties—to hire engineers building digital civic infrastructure for Japan. They’ve already created platforms to provide transparency for party expenditures, and to use AI to make legislation in the Diet easy, and are meeting with engineers from US-based Jigsaw Labs (a Google company) to learn from international examples of how AI can be used to power participatory democracy.

Team Mirai has yet to prove that it can get a second member elected to the Japanese Diet, let alone to win substantial power, but they’re innovating and demonstrating new ways of using AI to give people a way to participate in politics that we believe is likely to spread.

Organizing with AI

AI could be used in the US in similar ways. Following American federalism’s longstanding model of “laboratories of democracy,” we expect the most aggressive campaign innovation to happen at the state and local level.

D.C. Mayor Muriel Bowser is partnering with MIT and Stanford labs to use the AI-based tool deliberation.io to capture wide scale public feedback in city policymaking about AI. Her administration said that using AI in this process allows “the District to better solicit public input to ensure a broad range of perspectives, identify common ground, and cultivate solutions that align with the public interest.”

It remains to be seen how central this will become to Bowser’s expected re-election campaign in 2026, but the technology has legitimate potential to be a prominent part of a broader program to rebuild trust in government. This is a trail blazed by Taiwan a decade ago. The vTaiwan initiative showed how digital tools like Pol.is, which uses machine learning to make sense of real time constituent feedback, can scale participation in democratic processes and radically improve trust in government. Similar AI listening processes have been used in Kentucky, France, and Germany.

Even if campaigns like Bowser’s don’t adopt this kind of AI-facilitated listening and dialog, expect it to be an increasingly prominent part of American public debate. Through a partnership with Jigsaw, Scott Rasmussen’s Napolitan Institute will use AI to elicit and synthesize the views of at least five Americans from every Congressional district in a project called “We the People.” Timed to coincide with the country’s 250th anniversary in 2026, expect the results to be promoted during the heat of the midterm campaign and to stoke interest in this kind of AI-assisted political sensemaking.

In the year where we celebrate the American republic’s semiquincentennial and continue a decade-long debate about whether or not Donald Trump and the Republican party remade in his image is fighting for the interests of the working class, representation will be on the ballot in 2026. Midterm election candidates will look for any way they can get an edge. For all the risks it poses to democracy, AI presents a real opportunity, too, for politicians to engage voters en masse while factoring their input into their platform and message. Technology isn’t going to turn an uninspiring candidate into Barack Obama, but it gives any aspirant to office the capability to try to realize the promise that swept him into office.

This essay was written with Nathan E. Sanders, and originally appeared in The Fulcrum.

Friday Squid Blogging: Pilot Whales Eat a Lot of Squid

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/friday-squid-blogging-pilot-whales-eat-a-lot-of-squid.html

Short-finned pilot wales (Globicephala macrorhynchus) eat at lot of squid:

To figure out a short-finned pilot whale’s caloric intake, Gough says, the team had to combine data from a variety of sources, including movement data from short-lasting tags, daily feeding rates from satellite tags, body measurements collected via aerial drones, and sifting through the stomachs of unfortunate whales that ended up stranded on land.

Once the team pulled all this data together, they estimated that a typical whale will eat between 82 and 202 squid a day. To meet their energy needs, a whale will have to consume an average of 140 squid a day. Annually, that’s about 74,000 squid per whale. For all the whales in the area, that amounts to about 88,000 tons of squid eaten every year.

Research paper.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Blog moderation policy.

Upcoming Speaking Engagements

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/upcoming-speaking-engagements-50.html

This is a current list of where and when I am scheduled to speak:

  • My coauthor Nathan E. Sanders and I are speaking at the Rayburn House Office Building in Washington, DC at noon ET on November 17, 2025. The event is hosted by the POPVOX Foundation and the topic is “AI and Congress: Practical Steps to Govern and Prepare.”
  • I’m speaking on “Integrity and Trustworthy AI” at North Hennepin Community College in Brooklyn Park, Minnesota, USA, on Friday, November 21, 2025, at 2:00 PM CT. The event is cohosted by the college and The Twin Cities IEEE Computer Society.
  • Nathan E. Sanders and I will be speaking at the MIT Museum in Cambridge, Massachusetts, USA, on December 1, 2025, at 6:00 pm ET.
  • Nathan E. Sanders and I will be speaking at a virtual event hosted by City Lights on the Zoom platform, on December 3, 2025, at 6:00 PM PT.
  • I’m speaking and signing books at the Chicago Public Library in Chicago, Illinois, USA, on February 5, 2026. Details to come.

The list is maintained on this page.

The Role of Humans in an AI-Powered World

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/the-role-of-humans-in-an-ai-powered-world.html

As AI capabilities grow, we must delineate the roles that should remain exclusively human. The line seems to be between fact-based decisions and judgment-based decisions.

For example, in a medical context, if an AI was demonstrably better at reading a test result and diagnosing cancer than a human, you would take the AI in a second. You want the more accurate tool. But justice is harder because justice is inherently a human quality in a way that “Is this tumor cancerous?” is not. That’s a fact-based question. “What’s the right thing to do here?” is a human-based question.

Chess provides a useful analogy for this evolution. For most of history, humans were best. Then, in the 1990s, Deep Blue beat the best human. For a while after that, a good human paired with a good computer could beat either one alone. But a few years ago, that changed again, and now the best computer simply wins. There will be an intermediate period for many applications where the human-AI combination is optimal, but eventually, for fact-based tasks, the best AI will likely surpass both.

The enduring role for humans lies in making judgments, especially when values come into conflict. What is the proper immigration policy? There is no single “right” answer; it’s a matter of feelings, values, and what we as a society hold dear. A lot of societal governance is about resolving conflicts between people’s rights—my right to play my music versus your right to have quiet. There’s no factual answer there. We can imagine machines will help; perhaps once we humans figure out the rules, the machines can do the implementing and kick the hard cases back to us. But the fundamental value judgments will likely remain our domain.

This essay originally appeared in IVY.

Book Review: The Business of Secrets

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/book-review-the-business-of-secrets.html

The Business of Secrets: Adventures in Selling Encryption Around the World by Fred Kinch (May 24, 2024)

From the vantage point of today, it’s surreal reading about the commercial cryptography business in the 1970s. Nobody knew anything. The manufacturers didn’t know whether the cryptography they sold was any good. The customers didn’t know whether the crypto they bought was any good. Everyone pretended to know, thought they knew, or knew better than to even try to know.

The Business of Secrets is the self-published memoirs of Fred Kinch. He was founder and vice president of—mostly sales—at a US cryptographic hardware company called Datotek, from company’s founding in 1969 until 1982. It’s mostly a disjointed collection of stories about the difficulties of selling to governments worldwide, along with descriptions of the highs and (mostly) lows of foreign airlines, foreign hotels, and foreign travel in general. But it’s also about encryption.

Datotek sold cryptographic equipment in the era after rotor machines and before modern academic cryptography. The company initially marketed computer-file encryption, but pivoted to link encryption—low-speed data, voice, fax—because that’s what the market wanted.

These were the years where the NSA hired anyone promising in the field, and routinely classified—and thereby blocked—publication of academic mathematics papers of those they didn’t hire. They controlled the fielding of strong cryptography by aggressively using the International Traffic in Arms regulation. Kinch talks about the difficulties in getting an expert license for Datotek’s products; he didn’t know that the only reason he ever got that license was because the NSA was able to break his company’s stuff. He had no idea that his largest competitor, the Swiss company Crypto AG, was owned and controlled by the CIA and its West German equivalent. “Wouldn’t that have made our life easier if we had known that back in the 1970s?” Yes, it would. But no one knew.

Glimmers of the clandestine world peek out of the book. Countries like France ask detailed tech questions, borrow or buy a couple of units for “evaluation,” and then disappear again. Did they break the encryption? Did they just want to see what their adversaries were using? No one at Datotek knew.

Kinch “carried the key generator logic diagrams and schematics” with him—even today, it’s good practice not to rely on their secrecy for security—but the details seem laughably insecure: four linear shift registers of 29, 23, 13, and 7 bits, variable stepping, and a small nonlinear final transformation. The NSA probably used this as a challenge to its new hires. But Datotek didn’t know that, at the time.

Kinch writes: “The strength of the cryptography had to be accepted on trust and only on trust.” Yes, but it’s so, so weird to read about it in practice. Kinch demonstrated the security of his telephone encryptors by hooking a pair of them up and having people listen to the encrypted voice. It’s rather like demonstrating the safety of a food additive by showing that someone doesn’t immediately fall over dead after eating it. (In one absolutely bizarre anecdote, an Argentine sergeant with a “hearing defect” could understand the scrambled analog voice. Datotek fixed its security, but only offered the upgrade to the Argentines, because no one else complained. As I said, no one knew anything.)

In his postscript, he writes that even if the NSA could break Datotek’s products, they were “vastly superior to what [his customers] had used previously.” Given that the previous devices were electromechanical rotor machines, and that his primary competition was a CIA-run operation, he’s probably right. But even today, we know nothing about any other country’s cryptanalytic capabilities during those decades.

A lot of this book has a “you had to be there” vibe. And it’s mostly tone-deaf. There is no real acknowledgment of the human-rights-abusing countries on Datotek’s customer list, and how their products might have assisted those governments. But it’s a fascinating artifact of an era before commercial cryptography went mainstream, before academic cryptography became approved for US classified data, before those of us outside the triple fences of the NSA understood the mathematics of cryptography.

This book review originally appeared in AFIO.

On Hacking Back

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/on-hacking-back.html

Former DoJ attorney John Carlin writes about hackback, which he defines thus: “A hack back is a type of cyber response that incorporates a counterattack designed to proactively engage with, disable, or collect evidence about an attacker. Although hack backs can take on various forms, they are—­by definition­—not passive defensive measures.”

His conclusion:

As the law currently stands, specific forms of purely defense measures are authorized so long as they affect only the victim’s system or data.

At the other end of the spectrum, offensive measures that involve accessing or otherwise causing damage or loss to the hacker’s systems are likely prohibited, absent government oversight or authorization. And even then parties should proceed with caution in light of the heightened risks of misattribution, collateral damage, and retaliation.

As for the broad range of other hack back tactics that fall in the middle of active defense and offensive measures, private parties should continue to engage in these tactics only with government oversight or authorization. These measures exist within a legal gray area and would likely benefit from amendments to the CFAA and CISA that clarify and carve out the parameters of authorization for specific self-defense measures. But in the absence of amendments or clarification on the scope of those laws, private actors can seek governmental authorization through an array of channels, whether they be partnering with law enforcement or seeking authorization to engage in more offensive tactics from the courts in connection with private litigation.

И пак за руската хибридна война срещу демокрациите

Post Syndicated from Григор original http://www.gatchev.info/blog/?p=2672

Ето ви сериозно съкратен разказ за една от многото руски групи за пропагандни лъжи, кръстена от изследователите на Майкрософт “Storm-1516”. (Числото е пореден номер.)

—-

Започнала е като клон на Агенцията за Интернет проучвания – руска пропагандна група, създадена от Евгений Пригожин и регистрирана като „частна фирма“, за да се прикрие фактът, че е управлявана от отдела за активни мероприятия в чужбина на КГБ. Отделното съществуване на Storm-1516 е забелязано за пръв път от група изследователи на дезинформацията в медиите в университета Клемсън.

Основният им канал за разпространение са създавани в YouTube и X акаунти, представящи се за разследващи журналисти или уисълблоуъри. След това разпространява чрез тях пропагандни лъжи на английски, руски, финландски, арабски и френски езици. Често една и съща лъжа се пуска през няколко акаунта, за да оставя впечатление за достоверност.

Основният ѝ метод е заснемане на фалшиви видеота с участие на актьори или генерирането им с AI (по-рано – с дийпфейкване). Вероятната локация на екипа, който заснема видеотата с актьори, е Санкт Петербург. Те често се позовават на източници, които всъщност не съществуват. Пуснатите от тях видеота, както и другите пропагандни лъжи, след това биват споделяни от контролирани от ГРУ ботмрежи за ехо-акаунти.

В командването на групата вероятно взимат участие, или се намират под общо командване с нея, антилибералният „Центр геополитических экспертиз“ и друга пропагандна група, известна като „Фондация для борьбы с несправедливости“. Тясно свързани с нея са:

– групата Storm-1099, специализирана в създаване на фалшиви или имитационни пропагандни уебсайтове
– групата Storm-1679, специализирана в създаване на фалшиви документи и новинарски рапорти от името на достоверно изглеждащи, но фалшиви организации
– Ruza Flood, Volga Flood и Rybar – организации, които също разпространяват фалшива информация, често под името на реална личност (напр. Rybar – Михаил Звинчук) или фалшива персона, изпълнявана от актьор (напр. „Саня от Флорида“).

Свързана с нея изглежда и руската медийна компания Tenet Media, затворена през 2024 г. Основната ѝ дейност е била да плаща на десни блогъри в САЩ да снимат видеота с поръчано от нея съдържание.

Някои от основните теми, по които Storm-1516 генерират фалшиво съдържание, са:

– Намаляване на подкрепата за западна помощ за Украйна срещу руската агресия

През май 2024 г. те пускат фалшиво видео, което показва как украински войници горят чучело на Доналд Тръмп.

Много от фалшивките им лъжат, че украинските лидери злоупотребяват със западната помощ – купуват си яхти, имения, луксозни коли, наркотици и т.н. Имало е случаи, когато американски политици са се хващали на тези лъжи.

– Подкрепа за Доналд Тръмп

Честа тяхна теза е че украински тролски ферми работят срещу избирането на Доналд Тръмп. Целта ѝ е да прикрие отлично доказания факт, че всички руски тролски ферми бяха ангажирани в подкрепа на Доналд Тръмп. Едно от фалшивите видеота показва „служител на украинска тролска ферма“, който „си признава“, че ЦРУ изпълнява заговор, за да попречи на Тръмп да стане президент.

– Свързване на Украйна с Хамас

През октомври 2023 г. те пускат фалшиво видео, в което „ръководител на Хамас“ (лицето му е скрито) „благодари на Зеленски за доставките на оръжие и муниции“. В реалността между Украйна и Хамас няма връзки. Същият актьор в друго видео, пуснато преди Олимпийските игри в Париж, предупреждава, че „Хамас ще атакуват Олимпийските игри“. Видеото е широко разпространено чрез руските тролски мрежи. Френските и израелските служби потвърждават, че е фалшиво.

– Подкрепа за Доналд Тръмп

От началото на лятото на 2024 г. до самите избори за президент в САЩ групата, както и всички други тролски ресурси на ГРУ, е съсредоточена върху подкрепа за Доналд Тръмп. Storm-1516 основно произвеждат фалшиви видеота и новини, обвиняващи кандидатите на демократите в престъпления и разпространяващи конспиративни теории спрямо тях. През това време групата оперира над 100 фалшиви уебсайта, които очернят демократите и хвалят Тръмп и Русия. Частта от групата, която се грижи за тези сайтове, е ръководена от Джон Марк Дугън – бивш полицай от Флорида, конспиративен теорист, уличен в платена проруска пропаганда и потърсил политическо убежище в Русия.

Един от разпространяваните от групата фалшификати е, че Сикрет Сървис са открили в имението на Тръмп подслушвателни устройства, монтирани там от ФБР. Тръмп и Ванс също споделят тази лъжа в социалните мрежи.

Друг гласи, че при посещение в Замбия Камала Харис е застреляла нелегално Касуба – популярен женски черен носорог (видът е застрашен от изчезване). Фалшификатът е споделен от над милион фалшиви акаунта в Х, както и от работещи за Русия западни пропагандисти (Chay Bowes и т.н.)

Друго тяхно фалшиво видео, разпространено от Джон Дугън, „показва“ как поддръжници на Камала Харис атакуват сбирка на поддръжници на Тръмп и пребиват един от посетителите. Към това са прикрепени обичайните опорки за „агресивните леви екстремисти“, и коментари, целящи да засилят междурасови напрежения в САЩ.

На друго тяхно фалшиво видео „нелегален имигрант от Хаити“ разказва „как му е било платено да гласува за Харис многократно с различни шофьорски книжки“.

На друго тяхно фалшиво видео, пуснато в деня на изборите, „американски гласоподавател“ разказва как двама поддръжници на Харис нападнали и пребили поддръжник на Тръмп, за да му попречат да гласува.

В много агресивно разпространявано тяхно видео, видяно от почти 3 милиона души, жена твърди че е била блъсната като тинейджърка през 2011 г. от Камала Харис с кола и оставена да умре. Била цялата изпотрошена, претърпяла 11 операции преди да проходи отново, била и до момента в постоянни болки и т.н… Жената, посочена в различни източници като „Алисия Браун“, „Алиша Браун“ и т.н., е платена актриса. Рентгеновата снимка, показана във видеото за нейна, е взета от медицинско списание. Снимката на катастрофата от видеото е от катастрофа в Гуам през 2018 г. Новинарската агенция, посочена във видеото като източник на материала, не съществува (с изключение на фалшив уебсайт, създаден и поддържан от Storm-1516). Частта от видеото, на която Камала Харис напуска мястото на катастрофата, е дийпфейк… Видеото е споделено от много конгресмени-републиканци, включително Дж. Д. Ванс.

През октомври 2024 г., точно преди изборите, Storm-1516 прави съвместна кампания с QAnon за изкарване на Тим Валц (кандидат за вицепрезидент на демократите) педофил. Близко до QAnon радио излъчва „интервюта“ с „родител“ (в ролята – Джон Дугън) на „ученик“ на Валц, и със „студент на Валц от Казахстан“. (Проверката показва, че в училището, където преподава Валц, за последните 20 години не е имало студенти от Казахстан.) Части от излъчването са споделени масово от руски тролски ботмрежи и са видени от над 800 000 души в САЩ.

Един от акаунтите, споделили излъчването, е “BlackInsurrectionist” – създаден и управляван от Storm-1516. Има го във всички големи социални мрежи, следван е от водещи републикански политици (вкл. Тръмп-младши и Роджър Стоун). С тяхна помощ излъчването стига до около 33 милиона души.

В средата на октомври 2024 г. този акаунт пуска видео с е-майл, за който твърди, че е от малолетен, сексуално преследван от Валц. Многобройни признаци, че видеото е фалшификат, са моментално посочени от много негови зрители, но търсенията в Гугъл за „Tim Waltz pedophile“ скачат стократно. Няколко дни по-късно друг акаунт за конспиративни теории, също управляван от Storm-1516, пуска друго видео с подобни твърдения. Трето подобно видео, очевидно дело на същата група, е пуснато от акаунт на QAnon. Анализ на експерти от Wired показва, че всичките тези видеота са дийпфейкове.

На 19 октомври почти всички сайтове, управлявани от Джон Дугън, пускат голям репортаж, който цитира тези видеота (и ги представя за истински). Репортажът е цитиран от десни инфлуенсъри, между тях Кендис Оуенс и Джак Пособиец. На 21 октомври експерти на Wired успяват да докажат, че видеотата са дело на Storm-1516.

Друго фалшиво видео, създадено от същата група и пуснато през акаунт на QAnon 2 дни преди изборите, показва как член на изборна комисия проверява пратени по пощата бюлетини и къса тези, които са за Доналд Тръмп. Експертите веднага забелязват, че материалите и бюлетините, показани във видеото, не са истински – очевидно реквизиторът на групата се е изложил.

… Мога да напиша още няколко пъти по толкова за тях. А като погледнете поредния им номер, се досещайте колко още са като тях.

Правете си изводите.
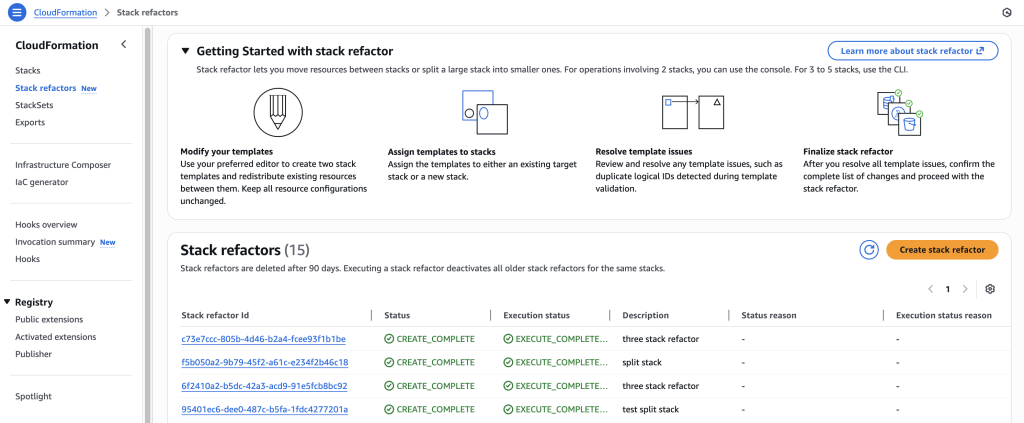
Prompt Injection in AI Browsers

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/prompt-injection-in-ai-browsers.html

This is why AIs are not ready to be personal assistants:

A new attack called ‘CometJacking’ exploits URL parameters to pass to Perplexity’s Comet AI browser hidden instructions that allow access to sensitive data from connected services, like email and calendar.

In a realistic scenario, no credentials or user interaction are required and a threat actor can leverage the attack by simply exposing a maliciously crafted URL to targeted users.

[…]

CometJacking is a prompt-injection attack where the query string processed by the Comet AI browser contains malicious instructions added using the ‘collection’ parameter of the URL.

LayerX researchers say that the prompt tells the agent to consult its memory and connected services instead of searching the web. As the AI tool is connected to various services, an attacker leveraging the CometJacking method could exfiltrate available data.

In their tests, the connected services and accessible data include Google Calendar invites and Gmail messages and the malicious prompt included instructions to encode the sensitive data in base64 and then exfiltrate them to an external endpoint.

According to the researchers, Comet followed the instructions and delivered the information to an external system controlled by the attacker, evading Perplexity’s checks.

I wrote previously:

Prompt injection isn’t just a minor security problem we need to deal with. It’s a fundamental property of current LLM technology. The systems have no ability to separate trusted commands from untrusted data, and there are an infinite number of prompt injection attacks with no way to block them as a class. We need some new fundamental science of LLMs before we can solve this.

Secure EKS clusters with the new support for Amazon EKS in AWS Backup

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/secure-eks-clusters-with-the-new-support-for-amazon-eks-in-aws-backup/

Today, we’re announcing support for Amazon EKS in AWS Backup to provide the capability to secure Kubernetes applications using the same centralized platform you trust for your other Amazon Web Services (AWS) services. This integration eliminates the complexity of protecting containerized applications while providing enterprise-grade backup capabilities for both cluster configurations and application data. AWS Backup is a fully managed service to centralize and automate data protection across AWS and on-premises workloads. Amazon Elastic Kubernetes Service (Amazon EKS) is a fully managed Kubernetes service to manage availability and scalability of the Kubernetes clusters. With this new capability, you can centrally manage and automate data protection across your Amazon EKS environments alongside other AWS services.

Until now, for backups, customers relied on custom solutions or third-party tools to back up their EKS clusters, requiring complex scripting and maintenance for each cluster. The support for Amazon EKS in AWS Backup eliminates this overhead by providing a single, centralized, and policy-driven solution that protects both EKS clusters (Kubernetes deployments and resources) and stateful data (stored in Amazon Elastic Block Store (Amazon EBS), Amazon Elastic File System (Amazon EFS), and Amazon Simple Storage Service (Amazon S3) only) without the need to manage custom scripts across clusters. For restores, customers were previously required to restore their EKS backups to a target EKS cluster which was either the source EKS cluster, or a new EKS cluster, requiring that an EKS cluster infrastructure is provisioned ahead of time prior to the restore. With this new capability, during a restore of EKS cluster backups, customers also have the option to create a new EKS cluster based on previous EKS cluster configuration settings and restore to this new EKS cluster, with AWS Backup managing the provisioning of the EKS cluster on the customer’s behalf.

This support includes policy-based automation for protecting single or multiple EKS clusters. This single data protection policy provides a consistent experience across all services AWS Backup supports. It allows creation of immutable backups to prevent malicious or inadvertent changes, helping customers meet their regulatory compliance needs. In case there is a customer data loss or cluster downtime event, customers can easily recover their EKS cluster data from encrypted, immutable backups using an easy-to-use interface and maintain business continuity of running their EKS clusters at scale.

How it works
Here’s how I set up support for on-demand backup of my EKS cluster in AWS Backup. First, I’ll show a walkthrough of the backup process, then demonstrate a restore of the EKS cluster.
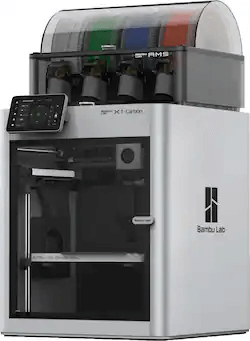
Backup
In the AWS Backup console, in the left navigation pane, I choose Settings and then Configure resources to opt in to enable protection of EKS clusters in AWS Backup.

Now that I’ve enabled Amazon EKS, in Protected resources I choose Create on-demand backup to create a backup for my already existing EKS cluster floral-electro-unicorn.

Enabling EKS in Settings ensures that it shows up as a Resource type when I create on-demand backup for the EKS cluster. I proceed to select the EKS resource type and the cluster.

I leave the rest of the information as default, then select Choose an IAM role to select a role (test-eks-backup) that I’ve created and customized with the necessary permissions for AWS Backup to assume when creating and managing backups on my behalf. I choose Create on-demand backup to finalize the process.


The job is initiated, and it will start running to back up both the EKS cluster state and the persistent volumes. If Amazon S3 buckets are attached to the backup, you’ll need to add the additional Amazon S3 backup permissions AWSBackupServiceRolePolicyForS3Backup to your role. This policy contains the permissions necessary for AWS Backup to back up any Amazon S3 bucket, including access to all objects in a bucket and any associated AWS KMS key.


The job is completed successfully and now EKS clusterfloral-electro-unicorn is backed up by AWS Backup.


Restore
Using the AWS Backup Console, I choose the EKS backup composite recovery point to start the process of restoring the EKS cluster backups, then choose Restore.


I choose Restore full EKS cluster to restore the full EKS backup. To restore to an existing cluster, I Choose an existing cluster then select the cluster from the drop-down list. I choose the Default order as the order in which individual Kubernetes resources will be restored.

I then configure the restore for the persistent storage resources, that will be restored alongside my EKS clusters.


Next, I Choose an IAM role to execute the restore action. The Protected resource tags checkbox is selected by default and I’ll leave it as is, then choose Next.

I review all the information before I finalize the process by choosing Restore, to start the job.


Selecting the drop-down arrow gives details of the restore status for both the EKS cluster state and persistent volumes attached. In this walkthrough, all the individual recovery points are restored successfully. If portions of the backup fail, it’s possible to restore the successfully backed up persistent stores (for example, Amazon EBS volumes) and cluster configuration settings individually. However, it’s not possible to restore full EKS backup. The successfully backed up resources will be available for restore, listed as nested recovery points under the EKS cluster recovery point. If there’s a partial failure, there will be a notification of the portion(s) that failed.


Benefits
Here are some of the benefits provided by the support for Amazon EKS in AWS Backup:

  • A fully managed multi-cluster backup experience, removing the overhead associated with managing custom scripts and third-party solutions.
  • Centralized, policy-based backup management that simplifies backup lifecycle management and makes it seamless to back up and recover your application data across AWS services, including EKS.
  • The ability to store and organize your backups with backup vaults. You assign policies to the backup vaults to grant access to users to create backup plans and on-demand backups but limit their ability to delete recovery points after they’re created.

Good to know
The following are some helpful facts to know:

  • Use either the AWS Backup Console, API, or AWS Command Line Interface (AWS CLI) to protect EKS clusters using AWS Backup. Alternatively, you can create an on-demand backup of the cluster after it has been created.
  • You can create secondary copies of your EKS backups across different accounts and AWS Regions to minimize risk of accidental deletion.
  • Restoration of EKS backups is available using the AWS Backup Console, API, or AWS CLI.
  • Restoring to an existing cluster will not override the Kubernetes versions, or any data as restores are non-destructive. Instead, there will be a restore of the delta between the backup and source resource.
  • Namespaces can only be restored to an existing cluster to ensure a successful restore as Kubernetes resources may be scoped at the cluster level.

Voice of the customer

Srikanth Rajan, Sr. Director of Engineering at Salesforce said “Losing a Kubernetes control plane because of software bugs or unintended cluster deletion can be catastrophic without a solid backup and restore plan. That’s why it’s exciting to see AWS rolling out the new EKS Backup and Restore feature, it’s a big step forward in closing a critical resiliency gap for Kubernetes platforms.”

Now available
Support for Amazon EKS in AWS Backup is available today in all AWS commercial Regions (except China) and in the AWS GovCloud (US) where AWS Backup and Amazon EKS are available. Check the full Region list for future updates.

To learn more, check out the AWS Backup product page and the AWS Backup pricing page.

Try out this capability for protecting your EKS clusters in AWS Backup and let us know what you think by sending feedback to AWS re:Post for AWS Backup or through your usual AWS Support contacts.

Veliswa.

Network Stats for Q3 2025: The Magnitude of AI Workflows

Post Syndicated from Brent Nowak original https://www.backblaze.com/blog/network-stats-for-q3-2025-the-magnitude-of-ai-workflows/

A textured background with the words Network Stats overlaid.

The way data moves is changing in the age of AI. As AI training, model tuning, and inferencing accelerate massive, unpredictable flows of data across clouds, our network telemetry here at Backblaze offers a real-world view into the AI data gravity shift: where data lives, how it moves, and what it takes to keep it accessible and affordable.

Over the past couple of years, we’ve shared Network Stats snapshots that shed light on how data moves across Backblaze’s storage cloud. This quarter, we’re taking that foundation further, and evolving this series into a full-fledged transparency report that stands alongside Drive Stats with regular quarterly reporting and stats you can analyze for yourself.

This report isn’t just about traffic patterns. It’s a look at how data movement is changing in the age of AI and what those shifts reveal about performance, cost, and resilience at scale. 

Tune in live for The Stats Lab webinar

Drive Stats was the beginning. Want to see the evolution? Check out the Backblaze Stats Lab webinar, bringing together content from all of our Stats articles. We’re going to chat about all things Backblaze and beyond—by the numbers.

Save My Seat

In this first report, we’re going to outline the fundamentals of our dataset, highlight standout examples for AI related traffic, and lay the foundation to start sharing our quarter-over-quarter metrics.

Dataset details 

Our internal tools allow us to capture network flow data, meaning transmission control protocol (TCP) conversations between parties on our network. Along with basic information such as who is talking and how many bits are being exchanged, we have the ability to record additional pieces of anonymized information like what country, what ISP, or if we’ve seen a particular IP address before. And for each of these metrics, we have numbers for the average, 95th percentile, and maximum values.

Let’s talk about the three elements that make up our dataset: time, values, and metadata.

1. Monthly time slices

For every month, for every region, and for each direction (egress and ingress), we are data warehousing the following metrics. We plan on either using month-by-month numbers, or rolling up into a quarterly value for Network Stats reports going forward.

Item Detail
Date range Every month
Location scope Every region (eg US-West, EU-Central)
Network traffic direction Ingress, egress

2. Metric values

For each monthly snapshot, we’re recording the following details in our data warehouse. Capturing the average, 95th weighted value, and the maximum allows us enough information to profile our traffic. 

The 95th value (discarding the highest 5% bursts) gives us a good profile for daily operations and the maximum helps profile bust traffic. 

The most interesting metrics that I’m excited to explore are the “bits per IP” values. This combination of “amount of traffic” transferred with “how many actors are involved” per network is a good proxy for what I’m calling the “magnitude” of the network flow. We’re exploring the first insight into this metric below in our chart section.

Defining the Network Stats Quarterly Data

Item Field(s) Detail
Name name
asn
Common name and BGP ASN of the network
Bits bits_avg
bits_95th
bits_max
Number of bits/second
Packets packets_avg
packets_95th
packets_max
Number of packets/second
Flows flow_avg
flow_95th
flow_max
Number of TCP flows
IPs ip_unique_avg
ip_unique_95th
ip_unique_max
Number of unique IP addresses
Bits per IP bits_ip_avg
bits_ip_95th
bits_ip_max
Number of bits per IP address
Protocol v4
v6
Amount of traffic using IPv4 vs IPv6

3. Additional metadata

One of the first custom additions to our dataset is a category field. This helps us define the BGP ASNs (Autonomous System Number), basically the organizations common name associated with a range of IP addresses, that we talk to and group them into categories such as neocloud, hyperscaler, CDN, or general ISP.

Additional Network Stats Metadata

Item Field Detail
category group The class of network carrying the traffic (Cloud, PNI, traditional Internet Transit, or Internal Backblaze-Backblaze)
category type The type of network receiving the traffic (Neocloud, Hosting/Compute provider, Hyperscaler, CDN, Regional ISP, more localised ISP, etc)

The global picture

We started capturing this dataset in August of 2025, so we don’t yet have a good amount of data to pull out quarter over quarter trends. But what we can do for now is take a look into some standout metrics for the month of August that we’re interested in tracking over time.

First let’s take a look at where all our traffic goes from a global perspective.

When we look at the data, one pattern stands out immediately: traffic associated with neocloud networks—cloud providers offering compute, GPU, or other AI-related services—already represents nearly a quarter of total ingress and egress across Backblaze’s network. That’s a meaningful signal. Historically CDN traffic has been the majority of our traffic as our B2 Object Storage has been growing. Now, we’re seeing clear evidence of a new class of workload emerging, and it’s AI-shaped.

Neocloud network behavior

Let’s look at the magnitude of our network traffic based on the category of the traffic destination. To help quantify our data set, we interact with around 123,000 unique IP addresses every month. 

CDN, hyperscaler, isp-regional, and isp-tier one traffic cluster in the same general range of bits per IP, but neoclouds have a couple outliers—the two purple data points in the upper right corner of the log scale graph. 

If we change the scale to linear (chart below), now we can see how much of an outlier the AI related traffic is in our sample range.

The “magnitude” (as we’re calling it) of the transfers we’re servicing for AI related flows to neoclouds is an order of magnitude greater than all our traffic patterns. This means that there are only a few unique IP addresses that we’re interacting with transferring large amounts of data in their flows.

The rise of AI-driven data movement

Over the past year, AI training and inference have transformed global data flows. Where traditional workloads move steadily, AI workloads move in bursts—rapid retrievals of massive datasets, short high-volume transfers for model training or tuning, and sustained outbound throughput for inferencing pipelines. The magnitude metric we’re introducing (bits per IP address) captures this shift. 

As shown in the charts above, AI-related traffic to neoclouds isn’t just heavier, it’s denser. Those purple data points represent a small number of IPs exchanging a disproportionate amount of data. That concentration of flow is a hallmark of AI compute pipelines, where a few high-bandwidth endpoints (often GPU clusters) interact with object storage to repeatedly feed and retrieve training data. 

In other words:

  • Fewer talkers, bigger flows. AI systems operate in fewer, more intense network sessions than traditional applications.
  • Shorter duration, higher peaks. Transfer patterns spike sharply, often corresponding to dataset replication or model checkpointing cycles.
  • Cross-cloud mobility. Much of this traffic routes between Backblaze and external compute platforms (classified as neoclouds) showing the rise of multi-cloud AI architectures.

The macro trend: The AI data gravity shift

This pattern reflects a broader macro trend in the cloud ecosystem: AI data gravity is pulling more storage and compute closer together. As AI models grow larger and datasets become more complex, organizations are rethinking where data “lives.” Instead of centralizing everything in one hyperscaler like AWS or Google Cloud Platform, they’re increasingly using cost-efficient, high-throughput storage clouds like Backblaze connected to specialized GPU clouds for compute (case in point: Why CoreWeave’s Object Storage Launch is Good for AI—and Everyone Building It).

This architectural shift explains the outlier traffic patterns we’re seeing on our network. Data isn’t just moving more—it’s moving smarter, following cost, performance, and regional availability cues. 

Why it matters

Tracking this kind of data movement and magnitude helps us, and more importantly our customers, understand a few key things:

  • Operational readiness for AI workloads: How our network scales under bursty, compute-linked demands. (For more on this check out Making the Backblaze Network AI Ready)
  • Cost predictability: Where and when ingress or egress volume spikes may occur.
  • Industry evolution: How AI is reshaping the underlying patterns of internet traffic.

What’s next?

This is just the first glimpse of that industry evolution. As our dataset matures, we’ll be able to watch these AI-linked flows change quarter over quarter, offering not just transparency, but a longitudinal view of how the data backbone of the AI economy takes shape. 

We’re planning to look at quarter over quarter number tracking for network types, IPv4 traffic vs IPv6 traffic, AI related workflows, cross-cloud connectivity trends, and more. We’re also planning to release the raw data quarterly going forward.

Anything specific you want to see? Let us know in the comments or reach out to our Evangelism team. 

We’re excited to share these insights from our network telemetry, the patterns we’re seeing, and what they mean for the broader data economy. This is the stuff we stay up at night studying, and sharing it publicly means we can all better understand the forces shaping digital infrastructure and build with greater confidence and foresight. 

The post Network Stats for Q3 2025: The Magnitude of AI Workflows appeared first on Backblaze Blog | Cloud Storage & Cloud Backup