Tag Archives: Uncategorized

Automatic Cheating Detection in Human Racing

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/automatic-cheating-detection-in-human-racing.html

This is a fascinating glimpse of the future of automatic cheating detection in sports:

Maybe you heard about the truly insane false-start controversy in track and field? Devon Allen—a wide receiver for the Philadelphia Eagles—was disqualified from the 110-meter hurdles at the World Athletics Championships a few weeks ago for a false start.

Here’s the problem: You can’t see the false start. Nobody can see the false start. By sight, Allen most definitely does not leave before the gun.

But here’s the thing: World Athletics has determined that it is not possible for someone to push off the block within a tenth of a second of the gun without false starting. They have science that shows it is beyond human capabilities to react that fast. Of course there are those (I’m among them) who would tell you that’s nonsense, that’s pseudoscience, there’s no way that they can limit human capabilities like that. There is science that shows it is humanly impossible to hit a fastball. There was once science that showed human beings could not run a four-minute mile.

Besides, do you know what Devon Allen’s reaction time was? It was 0.99 seconds. One thousandth of a second too fast, according to World Athletics’ science. They’re THAT sure that .01 seconds—and EXACTLY .01 seconds—is the limit of human possibilities that they will disqualify an athlete who has trained his whole life for this moment because he reacted one thousandth of a second faster than they think possible?

We in the computer world are used to this sort of thing. “The computer is always right,” even when it’s obviously wrong. But now computers are leaving the world of keyboards and screens, and this sort of thing will become more pervasive. In sports, computer systems are used to detect when a ball is out of bounds in tennis and other games and when a pitch is a strike in baseball. I’m sure there’s more—are computers detecting first downs in football?—but I’m not enough of a sports person to know them.

Credit Card Fraud That Bypasses 2FA

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/credit-card-fraud-that-bypasses-2fa.html

Someone in the UK is stealing smartphones and credit cards from people who have stored them in gym lockers, and is using the two items in combination to commit fraud:

Phones, of course, can be made inaccessible with the use of passwords and face or fingerprint unlocking. And bank cards can be stopped.

But the thief has a method which circumnavigates those basic safety protocols.

Once they have the phone and the card, they register the card on the relevant bank’s app on their own phone or computer. Since it is the first time that card will have been used on the new device, a one-off security passcode is demanded.

That verification passcode is sent by the bank to the stolen phone. The code flashes up on the locked screen of the stolen phone, leaving the thief to tap it into their own device. Once accepted, they have control of the bank account. They can transfer money or buy goods, or change access to the account.

Large-Scale Collection of Cell Phone Data at US Borders

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/large-scale-collection-of-cell-phone-data-at-us-borders.html

The Washington Post is reporting that the US Customs and Border Protection agency is seizing and copying cell phone, tablet, and computer data from “as many as” 10,000 phones per year, including an unspecified number of American citizens. This is done without a warrant, because “…courts have long granted an exception to border authorities, allowing them to search people’s devices without a warrant or suspicion of a crime.”

CBP’s inspection of people’s phones, laptops, tablets and other electronic devices as they enter the country has long been a controversial practice that the agency has defended as a low-impact way to pursue possible security threats and determine an individual’s “intentions upon entry” into the U.S. But the revelation that thousands of agents have access to a searchable database without public oversight is a new development in what privacy advocates and some lawmakers warn could be an infringement of Americans’ Fourth Amendment rights against unreasonable searches and seizures.

[…]

CBP conducted roughly 37,000 searches of travelers’ devices in the 12 months ending in October 2021, according to agency data, and more than 179 million people traveled that year through U.S. ports of entry.

More articles. Slashdot thread.

Implementing long running deployments with AWS CloudFormation Custom Resources using AWS Step Functions

Post Syndicated from DAMODAR SHENVI WAGLE original https://aws.amazon.com/blogs/devops/implementing-long-running-deployments-with-aws-cloudformation-custom-resources-using-aws-step-functions/

AWS CloudFormation custom resource provides mechanisms to provision AWS resources that don’t have built-in support from CloudFormation. It lets us write custom provisioning logic for resources that aren’t supported as resource types under CloudFormation. This post focusses on the use cases where CloudFormation custom resource is used to implement a long running task/job. With custom resources, you can manage these custom tasks (which are one-off in nature) as deployment stack resources.

The routine pattern used for implementing custom resources is via AWS Lambda function. However, when using the Lambda function as the custom resource provider, you must consider its trade-offs, such as its 15 minute timeout. Tasks involved in the provisioning of certain AWS resources can be long running and could span beyond the Lambda timeout. In these scenarios, you must look beyond the conventional Lambda function-based approach for custom resources.

In this post, I’ll demonstrate how to use AWS Step Functions to implement custom resources using AWS Cloud Development Kit (AWS CDK). Step Functions allow complex deployment tasks to be orchestrated as a step-by-step workflow. It also offers direct integration with any AWS service via AWS SDK integrations. By default the CloudFormation stack waits for 1 hour before timing out. The timeout can be increased to maximum 12 hours using wait conditions. In this post, you’ll also see how to use wait conditions with custom resource to run long running deployment tasks as part of a CloudFormation stack.

Prerequisites

Before proceeding any further, you must identify and designate an AWS account required for the solution to work. You must also create an AWS account profile in ~/.aws/credentials for the designated AWS account, if you don’t already have one. The profile must have sufficient permissions to run an AWS CDK stack. It should be your private profile and only be used during the course of this post. Therefore, it should be fine if you want to use admin privileges. Don’t share the profile details, especially if it has admin privileges. I recommend removing the profile when you’re finished with this walkthrough. For more information about creating an AWS account profile, see Configuring the AWS CLI.

Services and frameworks used in the post include CloudFormation, Step Functions, Lambda, DynamoDB, Amazon S3, and AWS CDK.

Solution overview

The following architecture diagram shows the application of Step Functions to implement custom resources.

Architecture diagram

Figure 1. Architecture diagram

  1. The user deploys a CloudFormation stack that includes a custom resource implementation.
  2. The CloudFormation custom resource triggers a Lambda function with the appropriate event which can be CREATE/UPDATE/DELETE.
  3. The custom resource Lambda function invokes Step Functions workflow and offloads the event handling responsibility. The CloudFormation event and context are wrapped inside the Step Function input at the time of invocation.
  4. The custom resource Lambda function returns SUCCESS back to CloudFormation stack indicating that the custom resource provisioning has begun. CloudFormation stack then goes into waiting mode where it waits for a SUCCESS or FAILURE signal to continue.
  5. In the interim, Step Functions workflow handles the custom resource event through one or more steps.
  6. Step Functions workflow prepares the response to be sent back to CloudFormation stack.
  7. Send Response Lambda function sends a success/failure response back to CloudFormation stack. This propels CloudFormation stack out of the waiting mode and into completion.

Solution deep dive

In this section I will get into the details of several key aspects of the solution

Custom Resource Definition

Following code snippet shows the custom resource definition which can be found here. Please note that we also define AWS::CloudFormation::WaitCondition and AWS::CloudFormation::WaitConditionHandle alongside the custom resource. AWS::CloudFormation::WaitConditionHandle resource sets up a pre-signed URL which is passed into the CallbackUrl property of the Custom Resource.

The final completion signal for the custom resource i.e. SUCCESS/FAILURE is received over this CallbackUrl. To learn more about wait conditions please refer to its user guide here. Note that, when updating the custom resource, you cannot use the existing WaitCondition-WaitConditionHandle resource pair. You need to create a new pair for tracking each update/delete operation on the custom resource.

/************************** Custom Resource Definition *****************************/
// When you intend to update CustomResource make sure that a new WaitCondition and 
// a new WaitConditionHandle resource is created to track CustomResource update.
// The strategy we are using here is to create a hash of Custom Resource properties.
// The resource names for WaitCondition and WaitConditionHandle carry this hash.
// Anytime there is an update to the custom resource properties, a new hash is generated,
// which automatically leads to new WaitCondition and WaitConditionHandle resources.
const resourceName: string = getNormalizedResourceName('DemoCustomResource');
const demoData = {
    pk: 'demo-sfn',
    sk: resourceName,
    ts: Date.now().toString()
};
const dataHash = hash(demoData);
const wcHandle = new CfnWaitConditionHandle(
    this, 
    'WCHandle'.concat(dataHash)
)
const customResource = new CustomResource(this, resourceName, {
    serviceToken: customResourceLambda.functionArn,
    properties: {
        DDBTable: String(demoTable.tableName),
        Data: JSON.stringify(demoData),
        CallbackUrl: wcHandle.ref
    }
});
        
// Note: AWS::CloudFormation::WaitCondition resource type does not support updates.
new CfnWaitCondition(
    this,
    'WC'.concat(dataHash),
    {
        count: 1,
        timeout: '300',
        handle: wcHandle.ref
    }
).node.addDependency(customResource)
/**************************************************************************************/

Custom Resource Lambda

Following code snippet shows how the custom resource lambda function passes the CloudFormation event as an input into the StepFunction at the time of invocation. CloudFormation event contains the CallbackUrl resource property I discussed in the previous section.

private async startExecution() {
    const input = {
        cfnEvent: this.event,
        cfnContext: this.context
    };
    const params: StartExecutionInput = {
        stateMachineArn: String(process.env.SFN_ARN),
        input: JSON.stringify(input)
    };
    let attempt = 0;
    let retry = false;
    do {
        try {
            const response = await this.sfnClient.startExecution(params).promise();
            console.debug('Response: ' + JSON.stringify(response));
            retry = false;

Custom Resource StepFunction

The StepFunction handles the CloudFormation event based on the event type. The CloudFormation event containing CallbackUrl is passed down the stages of StepFunction all the way to the final step. The last step of the StepFunction sends back the response over CallbackUrl via send-cfn-response lambda function as shown in the following code snippet.

/**
 * Send response back to cloudformation
 * @param event
 * @param context
 * @param response
 */
export async function sendResponse(event: any, context: any, response: any) {
    const responseBody = JSON.stringify({
        Status: response.Status,
        Reason: "Success",
        UniqueId: response.PhysicalResourceId,
        Data: JSON.stringify(response.Data)
    });
    console.debug("Response body:\n", responseBody);
    const parsedUrl = url.parse(event.ResourceProperties.CallbackUrl);
    const options = {
        hostname: parsedUrl.hostname,
        port: 443,
        path: parsedUrl.path,
        method: "PUT",
        headers: {
            "content-type": "",
            "content-length": responseBody.length
        }
    };
    await new Promise(() => {
        const request = https.request(options, function(response: any) {
	    console.debug("Status code: " + response.statusCode);
	    console.debug("Status message: " + response.statusMessage);
	    context.done();
    	})
	request.on("error", function(error) {
	    console.debug("send(..) failed executing https.request(..): " + error);
	    context.done();
	});
	request.write(responseBody);
	request.end();
    });
    return;
}

Demo

Clone the GitHub repo cfn-custom-resource-using-step-functions and navigate to the folder cfn-custom-resource-using-step-functions. Now, execute the script script-deploy.sh by passing the name of the AWS profile that you created in the prerequisites section above. This should deploy the solution. The commands are shown as follows for your reference. Note that if you don’t pass the AWS profile name ‘default’ the profile will be used for deployment.

git clone 
cd cfn-custom-resource-using-step-functions
./script-deploy.sh "<AWS- ACCOUNT-PROFILE-NAME>"

The deployed solution consists of 2 stacks as shown in the following screenshot

  1. cfn-custom-resource-common-lib: Deploys common components
    • DynamoDB table that custom resources write to during their lifecycle events
    • Lambda layer used across the rest of the stacks
  2. cfn-custom-resource-sfn: Deploys Step Functions backed custom resource implementation
CloudFormation stacks deployed

Figure 2. CloudFormation stacks deployed

For demo purposes, I implemented a custom resource that inserts data into the DynamoDB table. When you deploy the solution for the first time, like you just did in the previous step, it initiates a CREATE event resulting in the creation of a new custom resource using Step Functions. You should see a new record with unix epoch timestamp in the DynamoDB table, indicating that the resource was created as shown in the following screenshot. You can find the DynamoDB table name/arn from the SSM Parameter Store /CUSTOM_RESOURCE_PATTERNS/DYNAMODB/ARN

DynamoDB record indicating custom resource creation

Figure 3. DynamoDB record indicating custom resource creation

Now, execute the script script-deploy.sh again. This should initiate an UPDATE event, resulting in the update of custom resources. The code also automatically creates new WaitConditionHandle and WaitCondition resources required to wait for the update event to finish. Now you should see that the records in the DynamoDb table have been updated with new values for lastOperation and ts attributes as follows.

DynamoDB record indicating custom resource update

Figure 4. DynamoDB record indicating custom resource update

Cleaning up

To remove all of the stacks, run the script script-undeploy.sh as follows.

./script-undeploy.sh "<AWS- ACCOUNT-PROFILE-NAME>"

Conclusion

In this post I showed how to look beyond the conventional approach of building CloudFormation custom resources using a Lambda function. I discussed implementing custom resources using Step Functions and CloudFormation wait conditions. Try this solution in scenarios where you must execute a long running deployment task/job as part of your CloudFormation stack deployment.


About the author:

Damodar Shenvi

Damodar Shenvi Wagle is a Cloud Application Architect at AWS Professional Services. His areas of expertise include architecting serverless solutions, CI/CD and automation.

Massive Data Breach at Uber

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/massive-data-breach-at-uber.html

It’s big:

The breach appeared to have compromised many of Uber’s internal systems, and a person claiming responsibility for the hack sent images of email, cloud storage and code repositories to cybersecurity researchers and The New York Times.

“They pretty much have full access to Uber,” said Sam Curry, a security engineer at Yuga Labs who corresponded with the person who claimed to be responsible for the breach. “This is a total compromise, from what it looks like.”

It looks like a pretty basic phishing attack; someone gave the hacker their login credentials. And because Uber has lousy internal security, lots of people have access to everything. So once a hacker gains a foothold, they have access to everything.

This is the same thing that Mudge accuses Twitter of: too many employees have broad access within the company’s network.

More details. Slashdot thread.

EDITED TO ADD (9/20): More details.

Relay Attack against Teslas

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/relay-attack-against-teslas.html

Nice work:

Radio relay attacks are technically complicated to execute, but conceptually easy to understand: attackers simply extend the range of your existing key using what is essentially a high-tech walkie-talkie. One thief stands near you while you’re in the grocery store, intercepting your key’s transmitted signal with a radio transceiver. Another stands near your car, with another transceiver, taking the signal from their friend and passing it on to the car. Since the car and the key can now talk, through the thieves’ range extenders, the car has no reason to suspect the key isn’t inside—and fires right up.

But Tesla’s credit card keys, like many digital keys stored in cell phones, don’t work via radio. Instead, they rely on a different protocol called Near Field Communication or NFC. Those keys had previously been seen as more secure, since their range is so limited and their handshakes with cars are more complex.

Now, researchers seem to have cracked the code. By reverse-engineering the communications between a Tesla Model Y and its credit card key, they were able to properly execute a range-extending relay attack against the crossover. While this specific use case focuses on Tesla, it’s a proof of concept—NFC handshakes can, and eventually will, be reverse-engineered.

Upcoming Speaking Engagements

Post Syndicated from Schneier.com Webmaster original https://www.schneier.com/blog/archives/2022/09/upcoming-speaking-engagements-23.html

This is a current list of where and when I am scheduled to speak:

The list is maintained on this page.

Lifting and shifting a web application to AWS Serverless: Part 1

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/compute/lifting-and-shifting-a-web-application-to-aws-serverless-part-1/

Customers migrating to the cloud often want to get the benefits of serverless architecture. But what is the best approach and is it possible? There are many strategies to do a migration, but lift and shift is often the fastest way to get to production with the migrated workload.

You might also wonder if it’s possible to lift and shift an existing application that runs in a traditional environment to serverless. This blog post shows how to do this for a Mongo, Express, React, and Node.js (MERN) stack web app. However, the discussions presented in this post apply to other stacks too.

Why do a lift and shift migration?

Lift and shift, or sometimes referred to as rehosting the application, is moving the application with as few changes as possible. Lift and shift migrations often allow you to get the new workload in production as fast as possible. When migrating to serverless, lift and shift can bring a workload that is not yet in the cloud or in a serverless environment to use managed and serverless services quickly.

Migrating a non-serverless workload to serverless with lift and shift might not bring all the serverless benefits right away, but it enables the development team to refactor, using the strangler pattern, the parts of the application that might benefit from what serverless technologies offer.

Why migrate a web app to serverless?

Web apps hosted in a serverless environment benefit most from the capability of serverless applications to scale automatically and for paying for what you use.

Imagine that you have a personal web app with little traffic. If you are hosting in a serverless environment, you don’t pay a fixed price to have the servers up and running. Your web app has only a few requests and the rest of the time is idle.

This benefit applies to the opposite case. For an owner of a small ecommerce site running on a server, imagine if a social media influencer with millions of followers recommends one of their products. Suddenly, thousands of requests arrive and make the site unavailable. If the site is hosted on a serverless platform, the application will scale to the traffic that it receives.

Requirements for migration

Before starting a migration, it is important to define the nonfunctional requirements that you need the new application to have. These requirements help when you must make architectural decisions during the migration process.

These are the nonfunctional requirements of this migration:

  • Environment that scales to zero and scales up automatically.
  • Pay as little as possible for idle time.
  • Configure as little infrastructure as possible.
  • Automatic high availability of the application.
  • Minimal changes to the original code.

Application overview

This blog post guides you on how to migrate a MERN application. The original application is hosted in two different servers: One contains the Mongo database and another contains the Node/js/Express and ReactJS applications.

Application overview

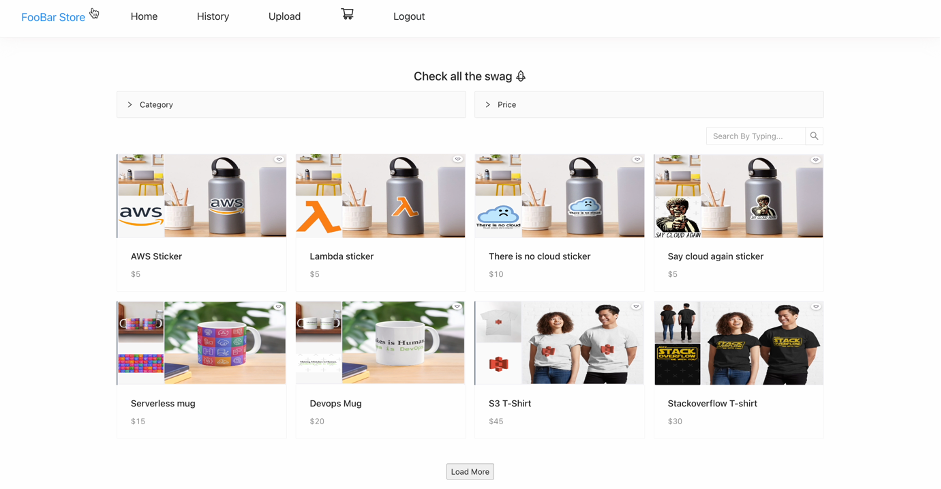
This demo application simulates a swag ecommerce site. The database layer stores the products, users, and the purchases history. The server layer takes care of the ecommerce business logic, hosting the product images, and user authentication and authorization. The web layer takes care of all the user interaction and communicates with the server layer using REST APIs.

How the application looks like

These are the changes that you must make to migrate to a serverless environment:

  • Database migration: Migrate the database from on-premises to MongoDB Atlas.
  • Backend migration: Migrate the NodeJS/Express application from on-premises to an AWS Lambda function.
  • Web app migration: Migrate the React web app from on-premises to AWS Amplify.
  • Authentication migration: Migrate the custom-built authentication to use Amazon Cognito.
  • Storage migration: Migrate the local storage of images to use Amazon S3 and Amazon CloudFront.

The following image shows the proposed solution for the migrated application:

Proposed architecture

Database migration

The database is already in a MongoDB vanilla container that has all the data for this application. As MongoDB is the database engine for our stack, their recommended solution to migrate to serverless is to use MongoDB Atlas. Atlas provides a database cluster in the cloud that scales automatically and you pay for what you use.

To get started, create a new Atlas cluster, then migrate the data from the existing database to the serverless one. To migrate the data, you can first dump all the content of the database to a dump folder and then restore it to the cloud:

mongodump --uri="mongodb://<localuser>:<localpassword>@localhost:27017"

mongorestore --uri="mongodb+srv://<user>:<password>@<clustername>.debkm.mongodb.net" .

After doing that, your data is now in the cloud. The next step is to change the configuration string in the server to point to the new database. To see this in action, check this video that shows a walkthrough of the migration.

Backend migration

Migrating the Node.js/Express backend is the most challenging of the layers to migrate to a serverless environment, as the server layer is a Node.js application that runs in a server.

One option for this migration is to use AWS Fargate. Fargate is a serverless container service that allows you to scale automatically and you pay as you go. Another option is to use AWS AppRunner, a container service that auto scales and you also pay as you go. However, neither of these options align with our migration requirements, as they don’t scale to zero.

Another option for the lift and shift migration of this Node.js application is to use Lambda with the AWS Lambda Web Adapter. The AWS Lambda Web Adapter is an open-source project that allows you to build web applications with familiar frameworks, like Express.js, Flask, SpringBoot, and run it on Lambda. You can learn more about this project in its GitHub repository.

Lambda Web Adapter

Using this project, you can create a new Lambda function that has the Express/NodeJS application as the function code. You can lift and shift all the code into the function. If you want a step-by-step tutorial on how to do this, check out this video.

const lambdaAdapterFunction = new Function(this,`${props.stage}-LambdaAdapterFunction`,
            {
                runtime: Runtime.NODEJS_16_X,
                code: Code.fromAsset('backend-app'),
                handler: 'run.sh',
                environment: {
                    AWS_LAMBDA_EXEC_WRAPPER: '/opt/bootstrap',
                    REGION: this.region,
                    ASYNC_INIT: 'true',
                },
                memorySize: 1024,
                layers: [layerLambdaAdapter],
                timeout: Duration.seconds(2),
                tracing: Tracing.ACTIVE,
            }
        );

The next step is to create an HTTP endpoint for the server application. There are three options for doing this: API Gateway, Application Load Balancer (ALB) , or to use Lambda Function URLs. All the options are compatible with Lambda Web Adapter and can solve the challenge for you.

For this demo, choose function URLs, as they are simple to configure and one function URL forwards all routes to the Express server. API Gateway and ALB require more configuration and have separate costs, while the cost of function URLs is included in the Lambda function.

Web app migration

The final layer to migrate is the React application. The best way to migrate the web layer and to adhere to the migration requirements is to use AWS Amplify to host it. AWS Amplify is a fully managed service that provides many features like hosting web applications and managing the CICD process for the web app. It provides client libraries to connect to different AWS resources, and many other features.

Migrating the React application is as simple as creating a new Amplify application in your AWS account and uploading the React application to a code repository like GitHub. This AWS Amplify application is connected to a GitHub branch, and when there is a new commit in this branch, AWS Amplify redeploys the code.

The Amplify application receives configuration parameters like the function URL endpoint (the server URL) using environmental variables.

const amplifyApp = new App(this, `${props.stage}-AmplifyReactShopApp`, {
            sourceCodeProvider: new GitHubSourceCodeProvider({
                owner: config.frontend.owner,
                repository: config.frontend.repository_name,
                oauthToken: SecretValue.secretsManager('github-token'),
            }),
            environmentVariables: {
                REGION: this.region,
                SERVER_URL: props.serverURL,
            },
        });

If you want to see a step-by-step guide on how to make your web layer serverless, you can check this video.

Next steps

However, if you test this migrated app, you will find two issues. The first one is that the user session is not sticky. Every time you log in, you are logged out unexpectedly from the application. The second one is that when you create a new product, you cannot upload new images of that product.

In part two, I analyze each of the problems in detail and find solutions. These issues arise because of the stateless and immutable characteristics of this solution. The next part of this article explains how to solve these issues, also it analyzes costs and performance of the solution.

Conclusion

In this article, you learn if it is possible to migrate a non-serverless web application to a serverless environment without changing much code. You learn different tools that can help you in this process, like the AWS Lambda Web Adaptor and AWS Amplify.

If you want to see the migration in action and learn all the steps for this, there is a playlist that contains all the tutorials for you to follow and learn how this is possible.

For more serverless learning resources, visit Serverless Land.

FBI Seizes Stolen Cryptocurrencies

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/fbi-seizes-stolen-cryptocurrencies.html

The Wall Street Journal is reporting that the FBI has recovered over $30 million in cryptocurrency stolen by North Korean hackers earlier this year. It’s only a fraction of the $540 million stolen, but it’s something.

The Axie Infinity recovery represents a shift in law enforcement’s ability to trace funds through a web of so-called crypto addresses, the virtual accounts where cryptocurrencies are stored. These addresses can be created quickly without them being linked to a cryptocurrency company that could freeze the funds.

In its effort to mask the stolen crypto, Lazarus Group used more than 12,000 different addresses, according to Chainalysis. Unlike bank transactions that happen through private networks, movement between crypto accounts is visible to the world on the blockchain.

Advanced blockchain-monitoring tools and cooperation from centralized crypto exchanges enabled the FBI to trace the crypto to where Lazarus Group tried to cash out, investigators said.

The money was laundered through the Tornado Cash mixer.

New Linux Cryptomining Malware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/new-linux-cryptomining-malware.html

It’s pretty nasty:

The malware was dubbed “Shikitega” for its extensive use of the popular Shikata Ga Nai polymorphic encoder, which allows the malware to “mutate” its code to avoid detection. Shikitega alters its code each time it runs through one of several decoding loops that AT&T said each deliver multiple attacks, beginning with an ELF file that’s just 370 bytes.

Shikitega also downloads Mettle, a Metasploit interpreter that gives the attacker the ability to control attached webcams and includes a sniffer, multiple reverse shells, process control, shell command execution and additional abilities to control the affected system.

[…]

The final stage also establishes persistence, which Shikitega does by downloading and executing five shell scripts that configure a pair of cron jobs for the current user and a pair for the root user using crontab, which it can also install if not available.

Shikitega also uses cloud hosting solutions to store parts of its payload, which it further uses to obfuscate itself by contacting via IP address instead of domain name. “Without [a] domain name, it’s difficult to provide a complete list of indicators for detections since they are volatile and they will be used for legitimate purposes in a short period of time,” AT&T said.

Bottom line: Shikitega is a nasty piece of code. AT&T recommends Linux endpoint and IoT device managers keep security patches installed, keep EDR software up to date and make regular backups of essential systems.

Another article.

Slashdot thread.

За британската кралица… и боклуците

Post Syndicated from original http://www.gatchev.info/blog/?p=2492

Кралица Елизабет Втора си отиде. И много боклуци моментално забълваха в каквито социални мрежи ги търпят отрова по неин адрес.

Не защото тя е причинила нещо лошо на който и да е от тях, пряко или косвено. А защото друго не могат и друго освен отрова в себе си нямат, дори към мъртвите. Това е, което ги прави боклуци.

Това ще бълват и за най-добрите и свестни хора, когато пред вас стане дума за тях в тяхно отсъствие. Правете си извода дали да им вярвате.

И това ще бълват и пред всички други за вас във ваше отсъствие, дори ако винаги сте им правили само добро. Правете си извода на какво да разчитате от тях.

Така че със смъртта си Елизабет Втора прави на всички нормални хора наоколо една последна, огромна услуга.

Дава ви възможността да забележите и запомните боклуците от този сорт. И да знаете какво говори за някого това, че те плюят отрова по него.

И възможността да се погрижите всеки да научи, че те са боклуци. За да знае защо те ще плюят пред него отрова по вас.

Responsible Disclosure for Cryptocurrency Security

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/responsible-disclosure-for-cryptocurrency-security.html

Stewart Baker discusses why the industry-norm responsible disclosure for software vulnerabilities fails for cryptocurrency software.

Why can’t the cryptocurrency industry solve the problem the way the software and hardware industries do, by patching and updating security as flaws are found? Two reasons: First, many customers don’t have an ongoing relationship with the hardware and software providers that protect their funds­—nor do they have an incentive to update security on a regular basis. Turning to a new security provider or using updated software creates risks; leaving everything the way it was feels safer. So users won’t be rushing to pay for and install new security patches.

Second, cryptocurrency is famously and deliberately decentralized, anonymized, and low friction. That means that the company responsible for hardware or software security may have no way to identify who used its product, or to get the patch to those users. It also means that many wallets with security flaws will be publicly accessible, protected only by an elaborate password. Once word of the flaw leaks, the password can be reverse engineered by anyone, and the legitimate owners are likely to find themselves in a race to move their assets before the thieves do. Even in the software industry, hackers routinely reverse engineer Microsoft’s patches to find the security flaws they fix and then try to exploit them before the patches have been fully installed.

He doesn’t have any good ideas to fix this. I don’t either. Just add it to the pile of blockchain’s many problems.

Facebook Has No Idea What Data It Has

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/facebook-has-no-idea-what-data-it-has.html

This is from a court deposition:

Facebook’s stonewalling has been revealing on its own, providing variations on the same theme: It has amassed so much data on so many billions of people and organized it so confusingly that full transparency is impossible on a technical level. In the March 2022 hearing, Zarashaw and Steven Elia, a software engineering manager, described Facebook as a data-processing apparatus so complex that it defies understanding from within. The hearing amounted to two high-ranking engineers at one of the most powerful and resource-flush engineering outfits in history describing their product as an unknowable machine.

The special master at times seemed in disbelief, as when he questioned the engineers over whether any documentation existed for a particular Facebook subsystem. “Someone must have a diagram that says this is where this data is stored,” he said, according to the transcript. Zarashaw responded: “We have a somewhat strange engineering culture compared to most where we don’t generate a lot of artifacts during the engineering process. Effectively the code is its own design document often.” He quickly added, “For what it’s worth, this is terrifying to me when I first joined as well.”

[…]

Facebook’s inability to comprehend its own functioning took the hearing up to the edge of the metaphysical. At one point, the court-appointed special master noted that the “Download Your Information” file provided to the suit’s plaintiffs must not have included everything the company had stored on those individuals because it appears to have no idea what it truly stores on anyone. Can it be that Facebook’s designated tool for comprehensively downloading your information might not actually download all your information? This, again, is outside the boundaries of knowledge.

“The solution to this is unfortunately exactly the work that was done to create the DYI file itself,” noted Zarashaw. “And the thing I struggle with here is in order to find gaps in what may not be in DYI file, you would by definition need to do even more work than was done to generate the DYI files in the first place.”

The systemic fogginess of Facebook’s data storage made answering even the most basic question futile. At another point, the special master asked how one could find out which systems actually contain user data that was created through machine inference.

“I don’t know,” answered Zarashaw. “It’s a rather difficult conundrum.”

I’m not surprised. These systems are so complex that no humans understand them anymore. That allows us to do things we couldn’t do otherwise, but it’s also a problem.

EDITED TO ADD: Another article.

The LockBit Ransomware Gang Is Surprisingly Professional

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/the-lockbit-ransomware-gang-is-surprisingly-professional.html

This article makes LockBit sound like a legitimate organization:

The DDoS attack last weekend that put a temporary stop to leaking Entrust data was seen as an opportunity to explore the triple extortion tactic to apply more pressure on victims to pay a ransom.

LockBitSupp said that the ransomware operator is now looking to add DDoS as an extortion tactic on top of encrypting data and leaking it.

“I am looking for dudosers [DDoSers] in the team, most likely now we will attack targets and provide triple extortion, encryption + date leak + dudos, because I have felt the power of dudos and how it invigorates and makes life more interesting,” LockBitSupp wrote in a post on a hacker forum.

The gang also promised to share over torrent 300GB of data stolen from Entrust so “the whole world will know your secrets.”

LockBit’s spokesperson said that they would share the Entrust data leak privately with anyone that contacts them before making it available over torrent.

They’re expanding: locking people out of their data, publishing it if the victim doesn’t pay, and DDoSing their network as an additional incentive.

… И молба за помощ

Post Syndicated from original http://www.gatchev.info/blog/?p=2489

Не, не за мен. А за – и от – вероятно най-добрия от живите български фантасти. Вие го познавате още като преводач и на много десетки прекрасни книги.

Начело с „Властелинът на пръстените“ – и всичко друго, написано от Толкин.

Точно така. Този писател е Любомир Николов – Нарви.

Молбата му за помощ – да помогнете да се разпродаде първия том на „Сивият път“ – можете да прочетете в блога му. И – да си го кажем директно – си е жива далавера. За общо 15 лева – на днешните военни цени! – получавате две прекрасни книги. Без да броим и печата „Спасител на Сивият път“.

И без да броим личната благодарност на Любо Николов.

А и вашия собствен интерес. Освен двете чудесни четива, вие плащате и това да има и още. Които също ще си струват. (Представяте ли си Любо Николов да напише нещо лошо?! И аз не мога.)

А, и още нещо. Любо предположи, че не може да продаде книгите си, понеже ги пусна в „Моята библиотека“ (ака Читанка.инфо). Според мен е точно обратното – именно запознанството с книга оттам я продава в днешни времена. Уви, днешният българин най-често не е чувал не само за Любо Николов, а и за Вазов, Яворов, Шекспир и Пушкин. (Съжалявам, ама Николета, Цеца, Васко Жабата, Азис и прочее не са им адекватни заместители. Въпреки че „циганинът“ Азис за разлика от днешния българин е чел Вазов, Яворов, Шекспир и Пушкин, а най-вероятно и Любомир Николов…) Така че нека му покажем, че не е прав – че и тези, които са се запознали с творчеството му оттам, също купуват книги!

Благодаря ви!

Montenegro Is the Victim of a Cyberattack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/09/montenegro-is-the-victim-of-a-cyberattack.html

Details are few, but Montenegro has suffered a cyberattack:

A combination of ransomware and distributed denial-of-service attacks, the onslaught disrupted government services and prompted the country’s electrical utility to switch to manual control.

[…]

But the attack against Montenegro’s infrastructure seemed more sustained and extensive, with targets including water supply systems, transportation services and online government services, among many others.

Government officials in the country of just over 600,000 people said certain government services remained temporarily disabled for security reasons and that the data of citizens and businesses were not endangered.

The Director of the Directorate for Information Security, Dusan Polovic, said 150 computers were infected with malware at a dozen state institutions and that the data of the Ministry of Public Administration was not permanently damaged. Polovic said some retail tax collection was affected.

Russia is being blamed, but I haven’t seen any evidence other than “they’re the obvious perpetrator.”

EDITED TO ADD (9/12): The Montenegro government is hedging on that Russia attribution. It seems to be a regular criminal ransomware attack. The Cuba Ransomware gang has Russian members, but that’s not the same thing as the government.