Wired is reporting on a new remote-access Trojan that is able to infect at least eighty different targets:
So far, researchers from Lumen Technologies’ Black Lotus Labs say they’ve identified at least 80 targets infected by the stealthy malware, including routers made by Cisco, Netgear, Asus, and DrayTek. Dubbed ZuoRAT, the remote access Trojan is part of a broader hacking campaign that has existed since at least the fourth quarter of 2020 and continues to operate.
The discovery of custom-built malware written for the MIPS architecture and compiled for small-office and home-office routers is significant, particularly given its range of capabilities. Its ability to enumerate all devices connected to an infected router and collect the DNS lookups and network traffic they send and receive and remain undetected is the hallmark of a highly sophisticated threat actor.
Amazon Keyspaces (for Apache Cassandra) is a scalable, highly available, and managed Apache Cassandra–compatible database service. With Amazon Keyspaces you don’t have to provision, patch, or manage servers, and you don’t have to install, maintain, or operate software. Amazon Keyspaces is serverless, so you only pay for the resources that you use and the service can automatically scale tables up and down in response to application traffic. You can use Amazon Keyspaces to store large volumes of data, such as entries in a log file or the message history for a chat application as Amazon Keyspaces offers virtually unlimited throughput and storage. You can also use Amazon Keyspaces to store information about devices for Internet of Things (IoT) applications or player profiles for games.
A popular use case in the wind energy sector is to protect wind turbines from wind speed. Engineers and analysts often want to see real-time aggregated wind turbine speed data to analyze the current situation out in the field. Furthermore, they need access to historical aggregated wind turbine speed data to build machine learning (ML) models which can help them take preventative actions on wind turbines. Customers often ingest high-velocity IoT data into Amazon Kinesis Data Streams and use Amazon Kinesis Data Analytics, AWS Lambda, or Amazon Kinesis Client Library (KCL) applications to aggregate IoT data in real-time and store it in Amazon Keyspaces, Amazon DynamoDB, or Amazon Timestream.
In this post, we demonstrate how to aggregate sensor data using Amazon Kinesis Data Analytics and persist aggregated sensor data in to Amazon Keyspaces using Apache Flink’s Apache Cassandra Connector.
Architecture
In the architecture diagram above, Lambda simulates wind speed sensor data and ingests sensor data into Amazon Kinesis Data Stream. Amazon Kinesis Data Analytics Apache Flink application reads wind speed sensor data from Amazon Kinesis Data Stream in real-time and aggregates wind speed sensor data using a five minutes tumbling window and storing aggregated wind speed sensor data into Amazon Keyspaces table. Aggregated wind speed sensor data stored in Amazon Keyspaces can be used by engineers and analysts to review real-time dashboards or to perform historical analysis on specific wind turbine.
Deploying resources using AWS CloudFormation
After you sign in to your AWS account, launch the AWS CloudFormation template by choosing Launch Stack:
The CloudFormation template configures the following resources in your account:
One Lambda function which simulates wind turbine data
One Amazon Kinesis Data Stream
One Amazon Kinesis Data Analytics Apache Flink application
One Amazon Keyspaces Table: turbine_aggregated_sensor_data
After you complete the setup, sign in to the Kinesis Data Analytics console. On the Kinesis Data Analytics applications page, choose the Streaming applications tab, where you can see the Streaming application in the ready status. Select the Streaming application, choose Run, and wait until the Streaming application is in running status. It can take a couple of minutes for the Streaming application to get into running status.
Now that we have deployed all of the resources using CloudFormation template, let’s review deployed resources and how they function.
Format of wind speed sensor data
Lambda simulates wind turbine speed data every one minute and ingests it into Amazon Kinesis Data Stream. Each wind turbine sensor data message consists of two attributes: turbineId and speed.
{
  "turbineId": "turbine-0001",
  "speed": 60
}
Schema of destination Amazon Keyspaces table
We’ll store aggregated sensor data in to destination turbine_aggregated_sensor_data Amazon Keyspaces table. turbine_aggregated_sensor_data table has on-demand capacity mode enabled. Amazon Keyspaces (for Apache Cassandra) on-demand capacity mode is a flexible billing option capable of serving thousands of requests per second without capacity planning. This option offers pay-per-request pricing for read and write requests so that you pay only for what you use. When you choose on-demand mode, Amazon Keyspaces can scale the throughput capacity for your table up to any previously reached traffic level instantly, and then back down when application traffic decreases. If a workload’s traffic level hits a new peak, then the service adapts rapidly to increase throughput capacity for your table.
Apache Flink code to aggregate and persist data in Amazon Keyspaces Table
The following code snippet demonstrates how incoming wind turbine messages are getting aggregated using a five-minute tumbling window and produces a DataStream of TurbineAggregatedRecord records.
The following code snippet demonstrates how Amazon Keyspaces table name and column names are annotated on the TurbineAggregatedRecord class.
@Table(keyspace = "sensor_data", name = "turbine_aggregated_sensor_data", readConsistency = "LOCAL_QUORUM", writeConsistency = "LOCAL_QUORUM")
public class TurbineAggregatedRecord {

@Column(name = "turbineid")
@PartitionKey(0)
private String turbineid = "";

@Column(name = "reported_time")
private long reported_time = 0;

@Column(name = "max_speed")
private long max_speed = 0;

@Column(name = "min_speed")
private long min_speed = 0;

@Column(name = "avg_speed")
private long avg_speed = 0;
The following code snippet demonstrates the implementation of Apache Cassandra Connector to sink aggregated wind speed sensor data TurbineAggregatedRecord into Amazon Keyspaces table. We’re using SigV4AuthProvider with Apache Cassandra Connector. The SigV4 authentication plugin lets you use IAM credentials for users or roles when connecting to Amazon Keyspaces. Instead of requiring a user name and password, this plugin signs API requests using access keys.
CassandraSink.addSink(result)
                .setClusterBuilder(
                        new ClusterBuilder() {

                            private static final long serialVersionUID = 2793938419775311824L;

                            @Override
                            public Cluster buildCluster(Cluster.Builder builder) {
                                return builder
                                        .addContactPoint("cassandra."+ region +".amazonaws.com")
                                        .withPort(9142)
                                        .withSSL()
                                        .withAuthProvider(new SigV4AuthProvider(region))
                                        .withLoadBalancingPolicy(
                                                DCAwareRoundRobinPolicy
                                                        .builder()
                                                        .withLocalDc(region)
                                                        .build())
                                        .withQueryOptions(queryOptions)
                                        .build();
                            }
                        })
                .setMapperOptions(() -> new Mapper.Option[] {Mapper.Option.saveNullFields(true)})
                .setDefaultKeyspace("sensor_data")
                .build();
Review output in Amazon Keyspaces Table
Once Amazon Kinesis Data Analytics Apache Flink application aggregates wind turbine sensor data and persists aggregated data in Amazon Keyspaces table, we can query and review aggregated data using Amazon Keyspaces CQL editor as illustrated in the following.
select * from sensor_data.turbine_aggregated_sensor_data
Clean up
To avoid incurring future charges, complete the following steps:
Empty Amazon S3 bucket created by AWS CloudFormation stack.
Delete AWS CloudFormation stack.
Conclusion
As you’ve learned in this post, you can build Amazon Kinesis Data Analytics Apache Flink application to read sensor data from Amazon Kinesis Data Streams, perform aggregations, and persist aggregated sensor data in Amazon Keyspaces using Apache Cassandra Connector. There are several use cases in IoT and Application development to move data quickly through the analytics pipeline and persist data in Amazon Keyspaces.
We look forward to hearing from you about your experience. If you have questions or suggestions, please leave a comment.
About the Author
Pratik Patel is a Sr Technical Account Manager and streaming analytics specialist. He works with AWS customers and provides ongoing support and technical guidance to help plan and build solutions using best practices and proactively helps in keeping customer’s AWS environments operationally healthy.
Is this comment out-of-date? I don’t think it describes what I’m seeing.
This pull request is massive, where do I start?
Where did this bug come from?
These questions all reflect the limitations of collaboratively-developed source code as a communication medium. While there are ways to mitigate these issues (code comments, style guides, documentation requirements), we still inevitably find ourselves spending hours on just trying to understand code. Luckily, the tools needed to solve these problems have been here all along!
Commits in Git repositories are more than just save points or logs of incremental progress in a larger project. In the words of GitHub’s “Git Guides“:
[Commits] are snapshots of your entire repository at specific times…based around logical units of change. Over time, commits should tell a story of the history of your repository and how it came to be the way that it currently is.
Commits are a firsthand historical record of exactly how and why each line of code came to be. They even come with human-readable messages! As a result, a repository’s commit history is the best tool a developer can use to explain and understand code.
It’s been my experience that commits are most effective when they’re tweaked and polished to deliberately convey a message to their audiences: reviewers, other contributors, and even your future self. This post will:
Introduce some guidelines for organizing and revising commits.
Outline pragmatic approaches for applying those guidelines.
Describe some of the practical applications of a well-crafted commit history.
Writing better commits
Software development involves a lot of creativity, so your commits will reflect the context of your changes, your goals, and your personal style. The guidelines below are presented to help you utilize that creative voice to make your commits effective tools of communication.
As you read these guidelines, don’t worry about how you’ll be able to utilize all of this advice in the midst of writing code. Although you may naturally incorporate them into your development process with practice, each can be applied iteratively after you’ve written all of your code.
Structure the narrative
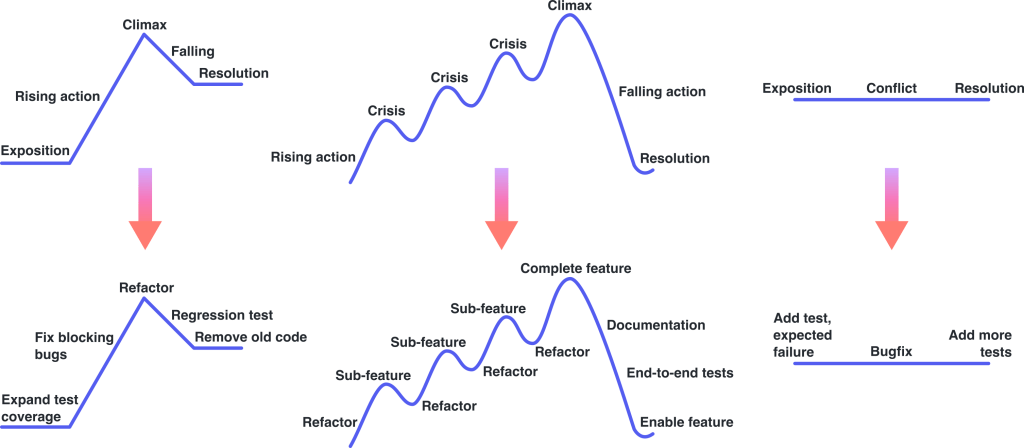
Like your favorite novel, a series of commits has a narrative structure that contextualizes the “plot” of your change with the code. Before any polishing, the narrative of a branch typically reflects an improvised stream of consciousness. It might contain:
A commit working on component A, followed by one on component B, followed by one finishing component A
A multi-commit detour into trying again and again to get the right CI syntax
A commit fixing a typo from an earlier commit
A commit with a mixed bag of all of the review feedback
A merge commit resolving conflicts with the main branch
Although an accurate retelling of your journey, a branch like this tells a “story” that is neither coherent nor memorable.
The problem
Disorganized commits that eschew a clear narrative will affect two people: the reviewer, and the developer themself.
Reviewing commit-by-commit is the easiest way to avoid being overwhelmed by the changes in a sufficiently large pull request. If those commits do not tell a singular, easy-to-follow story, the reviewer will need to context-switch as the author’s commits jump from topic to topic. To ensure earlier commits properly set up later ones (for example, verifying a newly-created function is used properly), the reviewer ultimately needs to piece together the narrative on their own; for each commit, figure out which earlier changes establish the relevant background context and tediously click back and forth between them. Alternatively, they’ll remember some vague details and simply assume earlier commits properly set up later ones, failing to identify potential issues.
But how does a scatterbrained narrative hurt the developer? A developer’s first instinct when working on a new project is often to hack on it until they get something functional. Fluctuating between “fun” and “frustrating,” this approach eventually yields good results, but it’s far from efficient. Jumping in without a plan – the mindset of following a narrative – makes that process slower than it needs to be.
The solution
Outline your narrative, and reorganize your commits to match it.
The narrative told by your commits is the vehicle by which you convey the meaning of your changes. Also, like a story, it can take on many structures or forms.
Your branch is your story to tell. While the narrative is up to you, here are some editorial tips on how to keep it organized:
DO
DON’T
Write an outline and include it in the pull request description.
Wait until the end to form the outline – try using it to guide your work!
Stick to one high-level concept per branch.
Go down a tangentially-related “rabbit hole”.
Add your “implement feature” commit immediately after the refactoring that sets it up.
Jump back and forth between topics throughout your branch.
Treat commits as “building blocks” of different types: bugfix, refactor, stylistic change, feature, etc.
Mix multiple building block types in a single commit.
Resize and stabilize the commits
Although the structure of a commit series can tell the high-level story of an author’s feature, it’s the code within each commit that creates software. Code itself can be complex, dense, and cryptic but in order to collaborate, others need to understand it.
The problem
The cognitive burden of parsing code is exacerbated by having either too much or not enough information presented at once. Too much, and your reader will need to read and understand multiple conceptually-different topics that could get jumbled, misinterpreted, or simply missed; too little, and your reader will develop an incomplete mental model of a change.
For a reviewer, one of the big benefits of a commit-by-commit review is – like individual lectures in a semester-long course – pacing the development of their mental model with small, easy-to-digest changes. When a large commit doesn’t provide that sustainable learning pace, the reviewer may fail fail to identify questionable architectural decisions because they conflate unrelated topics, or even miss a bug because it’s in a section seemingly irrelevant to the impacted feature.
You might think reviewers’ problems would be solved with commits as small as possible, but an incomplete change leaves them unable to evaluate it fully as they read it. When a later commit “completes” the change, a reviewer may not easily draw connections to the earlier context. This is made worse when a later commit undoes something from the earlier, partial commit. The “churn” in these situations leads to the same weakened mental model – and same consequences – as when dealing with too-large commits.
Poorly-sized commits present more tangible issues as well. Most apparent is the inability to roll back your repository to a commit (for example, when debugging a strange feature interaction). Incomplete changes often fail to build, so a developer will be stuck searching nearby commits for a fix. Similarly, a bug narrowed down to a massive commit requires teasing apart its intermixed changes, a potentially more difficult task than it was during the initial review due to loss of institutional project knowledge over time.
The solution
Make each commit both “small” and “atomic.”
To best convey your story, commits should minimize the effort needed to build a mental model of the changes they introduce. With effort tied to having a “just right” amount of information, the key to a good commit is fitting into quantified upper and lower bounds on that information.
A small commit is one with minimal scope; it does one “thing.” This often correlates to minimizing the modified lines of cone, but that isn’t a firm requirement. For example, changing the name of a commonly-used function may modify hundreds of lines of code, but its constrained scope makes it simple to both explain and review.
A commit is atomic when it is a stable, independent unit of change. In concrete terms, a repository should still build, pass tests, and generally function if rolled back to that exact commit without needing other changes. In an atomic commit, your reader will have everything they need to evaluate the change in the commit itself.
Explain the context
Commits are more than just the code they contain. Despite there being no shortage of jokes about them, commit messages are an extremely valuable – but often overlooked – component of a commit. Most importantly, they’re an opportunity to speak directly to your audience and explain a change in your own terms.
The problem
Even with a clear narrative and appropriately-sized commits, a niche change can still leave readers confused. This is especially true in large or open-source projects, where a reviewer or other future reader (even yourself!) likely won’t be clued into the implementation details or nuances of the code you’ve changed.
Code is rarely as self-evident as the author may believe, and even simple changes can be prone to misinterpretation. For example, what may appear to be a bug may instead be a feature implemented to solve an unrelated problem. Without understanding the intent of the original change, a developer may inadvertently modify an expected user-facing behavior. Conversely, something that appears intentional may have been a bug in the first place. A misinterpretation could cause a developer to enshrine a small mistake as a “feature” that hurts user experience for years.
Even in a best-case scenario, poorly explained changes will slow down reviewers and contributors as they attempt to interpret code, unnecessarily wasting everyone’s time and energy.
The solution
Describe what you’re doing and why you’re doing it in the commit message.
Because you’re writing for an audience, the content of a commit message should clearly communicate what readers need to understand. As the developer, you should already know the background and implementation well enough to explain them. Rather than write excessively long (and prone to obsoletion) code comments or put everything into a monolithic pull request description, you can use commit messages to provide piecewise clarification to each change.
“What” and “why” break down further into high- and low-level details, all of which can be framed as four questions to answer in each commit message:
What you’re doing
Why you’re doing it
High-level (strategic)
Intent (what does this accomplish?)
Context (why does the code do what it does now?)
Low-level (tactical)
Implementation (what did you do to accomplish your goal?)
Justification (why is this change being made?)
Building better projects
Using the guidelines established above, you can mitigate the challenges of common software development tasks including code review, finding bugs, and root cause analysis.
Code review
Reviewing even the largest pull requests can be a manageable, straightforward process if you are able to evaluate changes on a commit-by-commit basis. Each of the guidelines detailed earlier focuses on making the commits readable; to extract information from commits, you can use the guidelines as a template.
Determine the narrative by reading the pull request description and list of commits. If the commits seem to jump between topics or address, leave a comment asking for clarification or changes.
Lightly scan the message and contents of each commit, starting from the beginning of the branch. Verify smallness and atomicity by checking that the commit does one thing and that doesn’t include any incomplete implementations. Recommend splitting or combining commits that are incorrectly scoped.
Thoroughly read each commit. Ensure the commit message sufficiently explains the code by first checking that implementation matches the intent, then that the code matches the stated implementation. Use the context and justification to guide your understanding of the code. If any of the requisite information is missing, ask for clarification from the author.
Finally, with a complete mental model of the commit’s changes and the overarching narrative, confirm the code is efficient and bug-free.
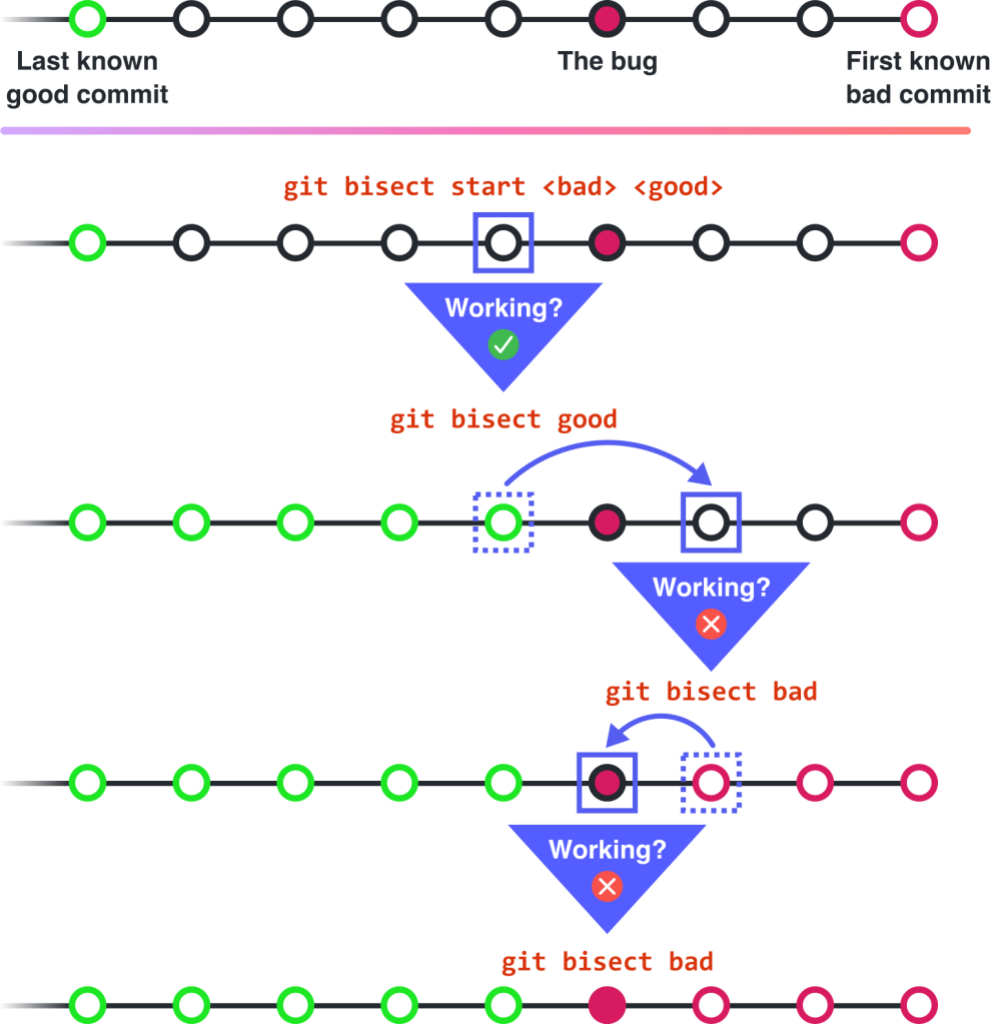
Finding bugs with git bisect
If you’ve ever found yourself with a broken deployment and no idea when the breakage was introduced, git bisect is the tool for you. Specifically, git bisect is a tool built into Git that, when given a known-good commit (for example, your last stable deployment) and a known-bad commit (the broken one), will perform a binary search of the commits in the middle to find which one introduced the error.
As useful as git bisect is, it absolutely requires that each commit it traverses is both atomic and small. If not atomic, you will be unable to test for repository stability at each commit; if not small, the source commit of your bug may be so large that you end up inefficiently reading code line-by-line to find the bug anyway.
Root cause analysis
Suppose you’ve used something like git bisect to isolate the source commit of a bug. If you’re lucky, the underlying problem is obvious and you can fix it immediately. More often than not, things aren’t so simple; the bug-causing code might be necessary for another feature, or does not make sense as the source of the error you’re seeing. You need to understand why the code was written, and to do that, you can again use the commit history to investigate.
There are two main tools to help you search through commits: git blame and git log.
git blame annotates the file with the commit that last changed it:
This can be particularly helpful in finding which commits modify the same area of code, which you can then read to determine if they interact poorly.
For a more generalized commit search, you can use git log. In its simplest form, git log will display a list of commits in reverse chronological order, starting at HEAD:
$ git log --oneline
09823ba09de1 README.md: update project title
abd52642da46 my-file.py: add README stat printout
7392d7dbb9ae my-file.py: rename from oldname.py
5ad823d1bc48 test.py: commonize test setup
603ab927a0dd oldname.py: create printout script
...
The displayed list of commits can also be filtered by file(s), by function name, by line range in a file, by commit message text, and more. As with git blame, these filtered lists of commits can help you build a complete mental model of the changes that comprise a particular file or function, ultimately guiding you to the root cause of your bug.
Final thoughts
Although subjective and sometimes difficult to quantify, commit quality can make a massive difference in developer quality-of-life on any project: old or new, large or small, open- or closed-source. To make commit refinement part of your own development process, some guidelines to follow are:
Organize your commits into a narrative.
Make each commit both small and atomic.
Explain the “what” and “why” of your change in the commit message.
These guidelines, as well as their practical applications, demonstrate how powerful commits can be when used to contextualize code. Regardless of what you do with them, commits will tell your project’s story; these strategies will help you make it a good one.
Version
1.62.0 of the Rust language has been released. Changes include a new cargo add command, default enum variants, an improved Linux
mutex implementation, a number of stabilized APIs, and more.
Amazon Web Services (AWS) is the first cloud service provider to produce an Open Security Control Assessment Language (OSCAL)–formatted system security plan (SSP) for the FedRAMP Project Management Office (PMO). OSCAL is the first step in the AWS effort to automate security documentation to simplify our customers’ journey through cloud adoption and accelerate the authorization to operate (ATO) process.
AWS continues its commitment to innovation and customer obsession. Our incorporation of the OSCAL format will improve the customer experience of reviewing and assessing security documentation. It can take an estimated 4,200 workforce hours for companies to receive an ATO, with much of the effort due to manual review and transcription of documentation. Automating this process through a machine-translatable language gives our customers the ability to ingest security documentation into a governance, risk management, and compliance (GRC) tool to automate much of this time-consuming task. AWS worked with an AWS Partner, to ingest the AWS SSP through their tool, Xacta.
This is a first step in several initiatives AWS has planned to automate the security assurance process across multiple compliance frameworks. We continue to look for ways to earn trust with our customers, and over the next year we will continue to release new solutions that customers can use to rapidly deploy secure and innovative services.
“Providing the SSP packages in OSCAL is a great milestone in security automation marking the beginning of a new era in cybersecurity. We appreciate the leadership in this area and look forward to working with all cyber professionals, in particular with the visionary cloud service providers, to help deliver secure innovation faster to the people they serve.”
– Dr. Michaela Iorga, OSCAL Strategic Outreach Director, NIST
To learn more about OSCAL, visit the NIST OSCAL website. To learn more about FedRAMP’s plans for OSCAL, visit the FedRAMP Blog.
Between tech layoffs and recession fears, economic uncertainty is at a high. If you’re battening down the hatches for whatever comes next, you might be taking a closer look at your cloud spend. Even before the bear market, 59% of cloud decision makers named “optimizing existing use of cloud (cost savings)” as their top cloud initiative of 2022 according to the Flexera State of the Cloud report.
Cloud storage is one piece of your cloud infrastructure puzzle, but it’s one where some simple considerations can save you anywhere from 25% up to 80%. As such, understanding cloud storage pricing is critical when you are comparing different solutions. When you understand pricing, you can better decide which provider is right for your organization.
In this post, we won’t look at 1:1 comparisons of cloud storage pricing, but you can check out a price calculator here. Instead, you will learn tips to help you make a good cloud storage decision for your organization.
Evaluating Your Cloud Storage? Gather These Facts
Looking at the pricing options of different cloud providers only makes sense when you know your needs. Use the following considerations to clarify your storage needs to approach a cloud decision thoughtfully:
How do you plan to use cloud storage?
How much does cloud storage cost?
What features are offered?
1. How Do You Plan to Use Cloud Storage?
Some popular use cases for cloud storage include:
Backup and archive.
Origin storage.
Migrating away from LTO/tape.
Managing a media workflow.
Backup and Archive
Maintaining data backups helps make your company more resilient. You can more easily recover from a disaster and keep serving customers. The cloud provides a reliable, off-site place to keep backups of your company workstations, servers, NAS devices, and Kubernetes environments.
Case Study: Famed Photographer Stores a Lifetime of Work
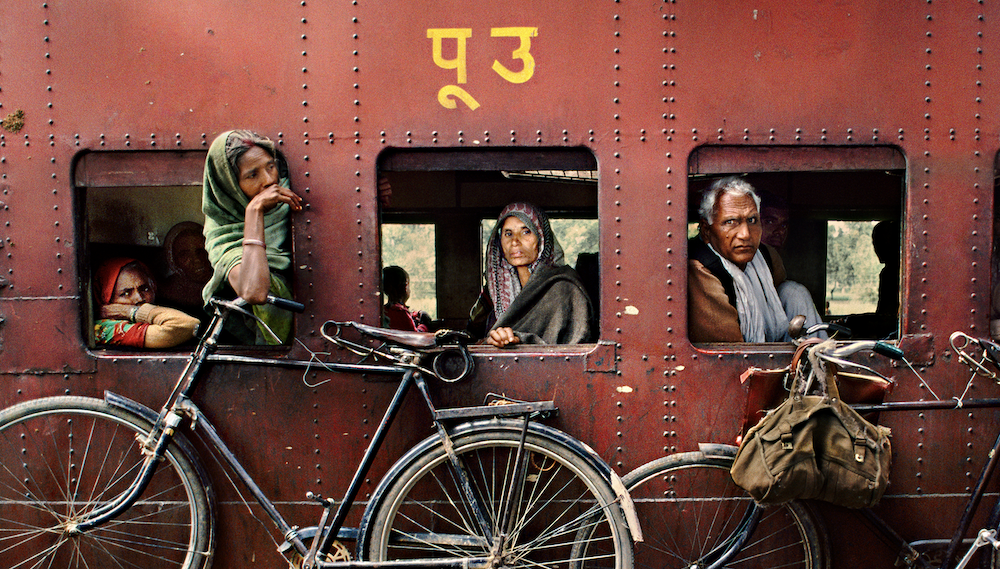
Photographer Steve McCurry, renowned for his 1984 photo of the “Afghan Girl” which has been on the cover of National Geographic several times, backed up his life’s work in the cloud when his team didn’t want to take chances with his irreplaceable archives.
Origin Storage
If you run a website, video streaming service, or online gaming community, you can use the cloud to serve as your origin store where you keep content to be served out to your users.
Case Study: Serving 1M+ Websites From Cloud Storage
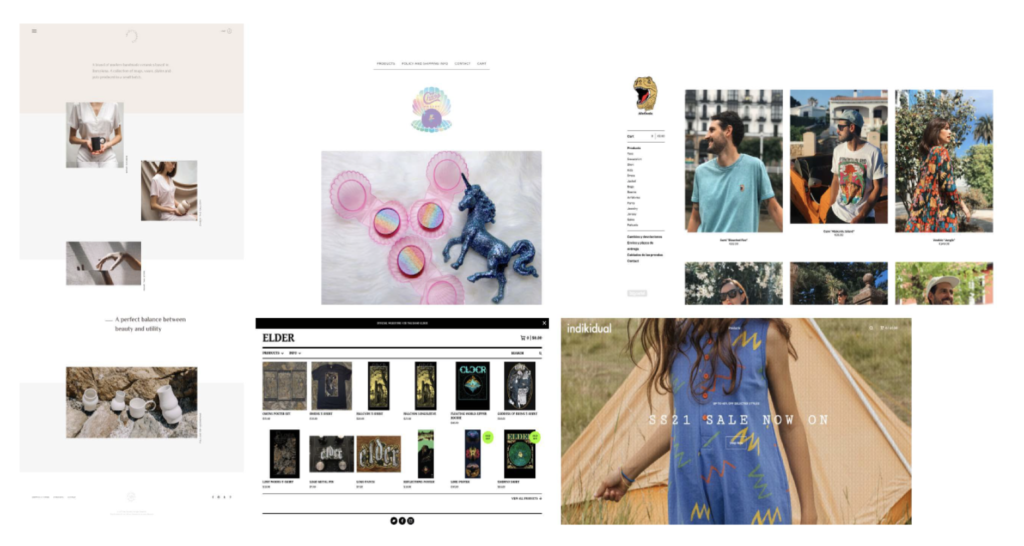
Big Cartel hosts more than one million e-commerce websites. To increase resilience, the company recently started using a second cloud provider. By adopting a multi-cloud infrastructure, the business now has lower costs and less risk of failure.
Migrating Away From LTO/Tape
Managing a tape library can be time-consuming and comes with high CapEx spending. With inflation, replacing tapes costs more, shipping tapes off-site costs more, and physical storage space costs more. The cloud provides an affordable alternative to storing data on tape where you pass the decreased margins off to a cloud provider—they have to worry about provisioning enough physical storage devices and space while you pay as you go.
Managing Media Workflow
Your department or organization may need to work with large media files to create movies or digital videos. Cloud storage provides an alternative to provisioning huge on-premises servers to handle large files.
Case Study: Using the Cloud to Store Media
Hagerty Insurance stored a huge library of video assets on an aging server that couldn’t keep up. They implemented a hybrid cloud solution for cloud backup and sync, saving the team over 200 hours per year searching for files and waiting for their slow server to respond.
2. How Much Does Cloud Storage Cost?
Cloud storage costs are calculated in a variety of different ways. Before considering any specific vendors, knowing the most common options, variables, and fees is helpful, including:
Flat or single-tier pricing vs. tiered pricing.
Hot vs. cold storage.
Storage location.
Minimum retention periods.
Egress fees.
Flat or Single-tier Pricing vs. Tiered Pricing
A flat or single-tier pricing approach charges the user based on the storage volume, and cost is typically expressed per gigabyte stored. There is only one tier, making budgeting and planning for cloud expenses simple.
On the other hand, some cloud storage services use a tiered storage pricing model. For example, a provider may have a small business pricing tier and an enterprise tier. Note that different pricing tiers may include different services and features. Today, your business might use an entry-level pricing tier but need to move to a higher-priced tier as you produce more data.
Hot vs. Cold Storage
Hot storage is helpful for data that needs to be accessible immediately (e.g., last month’s customer records). By contrast, cold storage is helpful for data that does not need to be accessed quickly (e.g., tax records from five years ago). For more insight on hot vs. cold storage, check out our post: “What’s the Diff: Hot and Cold Data Storage.” Generally speaking, cold storage is the cheapest, but that low price comes at the cost of speed. For data that needs to be accessed frequently or even for data where you’re not sure how often you need access, hot storage is better.
Storage Location
Some organizations need their cloud storage to be located in the same country or region due to regulations or just preference. But some storage vendors charge different prices to store data in different regions. Keeping data in a specific location may impact cloud storage prices.
Minimum Retention Periods
Most folks think of “retention” as a good thing, but some storage vendors enforce minimum retention periods that essentially impose penalties for deleting your data. Some vendors enforce minimum retention periods of 30, 60, or even 90 days. Deleting your data could cost you a lot, especially if you have a backup approach where you retire older backups before the retention period ends.
Egress Fees
Cloud companies charge egress fees when customers want to move their data out of the provider’s platform. These fees can be egregiously high, making it expensive for customers to use multi-cloud infrastructures and therefore locking customers into their services.
3. What Additional Features Are Offered?
While price is likely one of your biggest considerations, choosing a cloud storage provider solely based on price can lead to disappointment. There are specific cloud storage features that can make a big difference in your productivity, security, and convenience. Keep these features and capabilities in mind when comparing different cloud storage solutions.
Security Features
You may be placing highly sensitive data like financial records and customer service data in the cloud, so features like server-side encryption could be important. In addition, you might look for a provider that offers Object Lock so you can protect data using a Write Once, Read Many (WORM) model.
Data Speed
Find out how quickly the cloud storage provider can provide data regarding upload and download speed. Keep in mind that the speed of your internet connection also impacts how fast you can access data. Data speed is critically important in several industries, including media and live streaming.
Customer Support
If your company has a data storage problem outside of regular business hours, customer support becomes critically important. What level of support can you expect from the provider? Do they offer expanded support tiers?
Partner Integrations
Partner integrations make it easier to manage your data. Check if the cloud storage provider has integrations with services you already use.
The Next Step in Choosing Cloud Storage
Understanding cloud storage pricing requires a holistic view. First, you need to understand your organization’s data needs. Second, it is wise to understand the typical cloud storage pricing models commonly used in the industry. Finally, cloud storage pricing needs to be understood in the context of features like security, integrations, and customer service. Once you consider these steps, you can approach a decision to switch cloud providers or optimize your cloud spend more rigorously and methodically.
The kernel does not lack for memory allocators, so one might well question
the need for yet another one. As this
patch set from Alexei Starovoitov makes clear, though, the BPF
subsystem feels such a need. The proposed new allocator is intended to
increase the reliability of allocations made within BPF programs, which might
be run in just about any execution context.
Security updates have been issued by Debian (firefox-esr, firejail, and ublock-origin), Fedora (chromium, firefox, thunderbird, and vim), Mageia (kernel and kernel-linus), Oracle (389-ds-base and python-virtualenv), SUSE (chromium), and Ubuntu (cloud-init).
Welcome back to The Lost Bots! In the first installment of Season 2, Rapid7 Detection and Response (D&R) Practice Advisor Jeffrey Gardner and his new co-host Stephen Davis, Lead D&R Sales Technical Advisor, give us their five pillars of success for deploying a security information and event management (SIEM) solution. They tell us which pillars are their favorites and how security practitioners — including our hosts themselves — sometimes misstep in these areas.
Watch below for a rundown of how to successfully deploy a SIEM, all in a cool 10 minutes. (Fair warning: Your actual SIEM deployment might take slightly longer than it takes to watch this episode.)
Throughout Season 2, Jeffrey and Stephen will talk through some of the biggest topics and most pressing questions in D&R and cybersecurity, both one-on-one and with guests. We’ll be publishing new episodes on the last Thursday of every month. See you in July!
NEVER MISS A BLOG
Get the latest stories, expertise, and news about security today.
Managed Transforms is the next step on a journey to make HTTP header modification a trivial task for our customers. In early 2021 the only way for Cloudflare customers to modify HTTP headers was by writing a Cloudflare Worker. We heard from numerous customers who wanted a simpler way.
In June 2021 we introduced Transform Rules, giving customers a simple UI letting them specify what the custom HTTP header’s name and value is—either a static string (i.e. X-My-CDN: Cloudflare) or a dynamically populated value (i.e. X-Bot-Score: cf.bot_management.score).
This made the job much simpler, however there is still a good amount of thought required—with a number of potential drop-off points on the user journey. For example, in order to dynamically populate the bot score into the value of an HTTP request header, the user needs to know the correct field name. To find that they’ll need to go to the documentation site, find the correct section, etc.
When we analyzed how our customers use Transform Rules we found a set of very common use cases in the data. Four of the top eight fields used were relating to bot management; customers wanting to have the bot score, JA3 hash, etc. of each request added as an HTTP header. A further three of the top 10 fields were relating to the geographic location of the visitor (their city, country and ASN). We also saw over 400 Transform Rules being used just to remove X-Powered-By. That means potentially 400 users went to the same part of the dashboard, typed the same header name, read the same documentation and selected the same action.
Much as we set out to productize the common Cloudflare Worker use case of HTTP header modification into Transform Rules, we have now set out to productize and further simplify the common Transform Rules use cases into Managed Transforms.
The intention is to continue to identify common reasons for use of a Transform Rule and where possible package them up into a single click solution.
We always want to make our user’s lives as easy as possible, and finding a way to stop hundreds of people typing the same thing and clicking the same buttons, to achieve the exact same outcome, seems a great way to continue that mission.
An even simpler solution
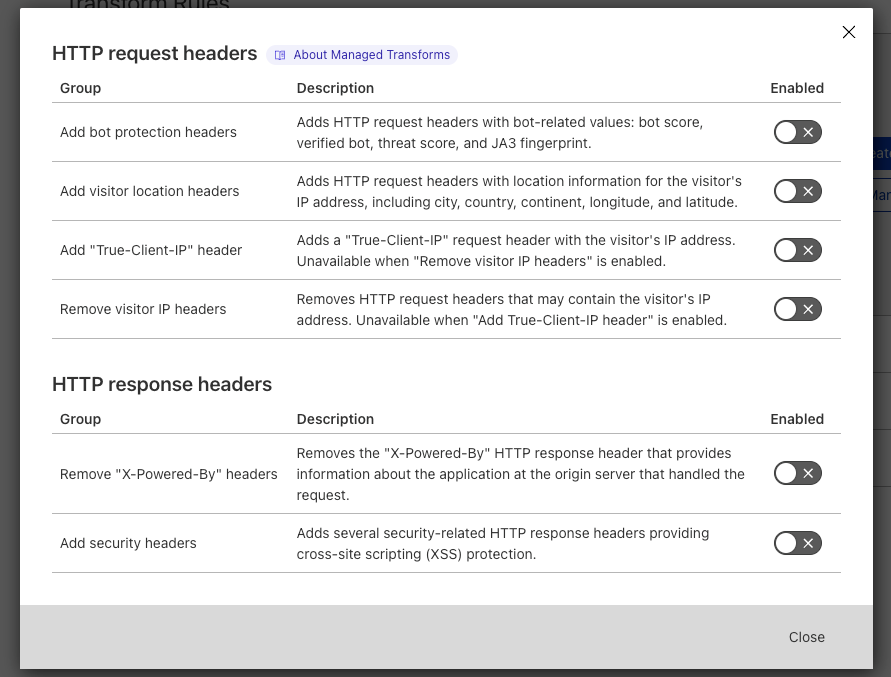
Managed Transforms is a dedicated section of Transform Rules offering one-click HTTP header modifications. Want to add relevant Cloudflare Bot Management information as custom HTTP headers? One click. Want to add geographic information (country, etc.) as custom HTTP headers? One click.
Managed Transforms can be found in ‘Rules > Transform Rules’ and clicking on the ‘Managed Transforms’ button. To benefit from Managed Transforms, users simply toggle the appropriate settings, and we take care of the rest.
For example, to enrich every HTTP request with Cloudflare’s Bot Management information users would enable ‘Add bot protection headers’. This setting ensures we add four new HTTP request headers to every HTTP request. SIEM (Security Information and Event Management) products can then be configured to correctly collect and chart these new headers, allowing customers to see the bot score of every HTTP request, how many requests are coming from verified bots, and so on.
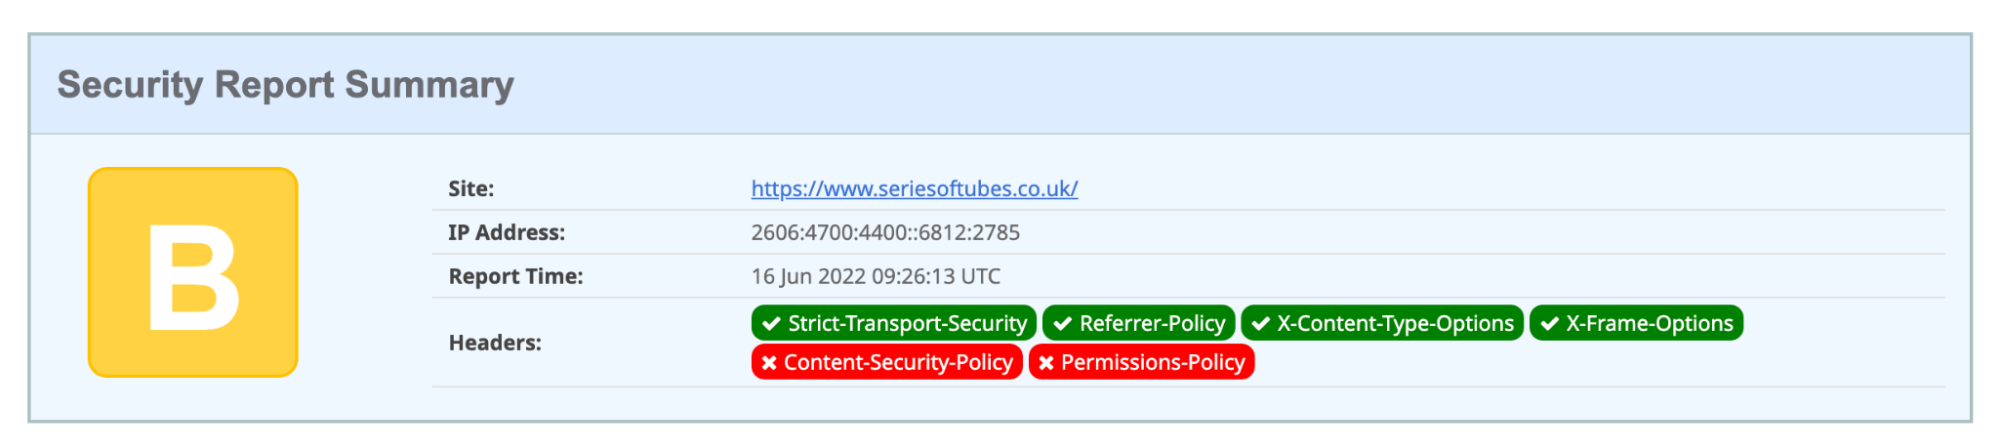
Another great use case is the ‘Add security headers’ toggle. On a completely standard, default zone, a user can improve their website’s security score from an F to a C in just one click. Enabling HSTS improves the score to a B (scores correct as of June 7, 2022).
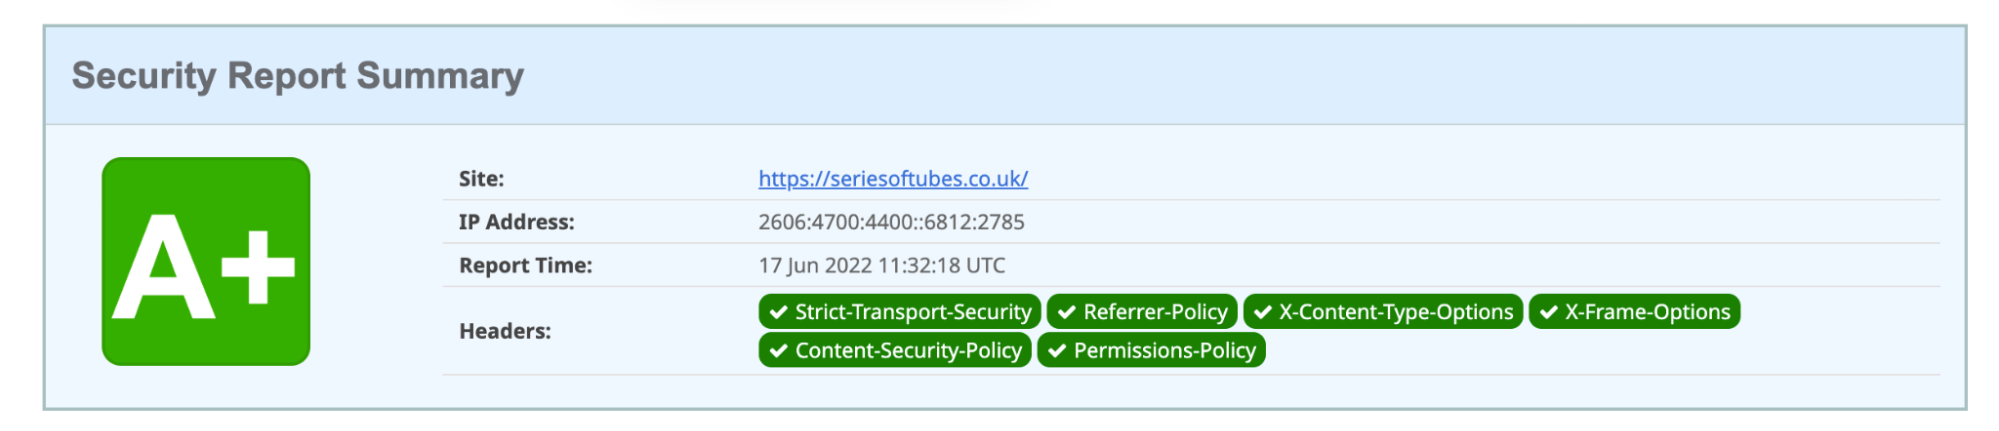
Adding a Content-Security-Policy (used to mitigate Cross-Site Scripting (‘XSS’) attacks) or a Permission-Policy (used to give websites the ability to allow or block the use of browser features) increases the score to an ‘A’; the addition of both improves the score to the maximum: A+.
During the design of Managed Transforms we chose not to include default Content-Security-Policy and Permission-Policy HTTP response headers within the ‘Add security headers’ toggle as we found these particular headers to be very specific to each individual website. Any default policies we tried either caused incorrect loading of the website content, or were too open to be of any value. So we decided to remove them from scope.
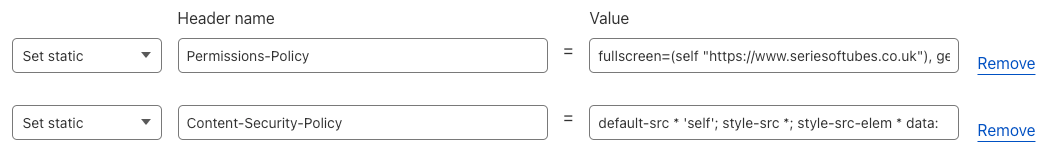
However, users can still add these HTTP response headers and their appropriate values in a handful of clicks by creating a new Transform Rule:
The HTTP response headers entered here will be added alongside the HTTP response headers added by Managed Transforms to give an A+ score.
Try it now
Managed Transforms can be used to improve operations, remove sensitive data, and increase security, amongst other common use cases.
Imports of Syrian phosphates into Europe have boomed over the past several years. The importers include Serbia and Ukraine, as well EU members Italy, Bulgaria, Spain, and Poland. Security firms…
Главное из расследования: За последние несколько лет объемы импорта сирийских фосфатов в Европу резко возросли. В числе импортеров Сербия и Украина, а также страны ЕС: Италия, Болгария, Испания и Польша. …
• Вносът на сирийски фосфати в Европа бележи бум през последните няколко години. • Сред вносителите са Сърбия и Украйна, но също и членките на ЕС Италия, България, Испания и…
It’s wonderful hearing from people in the community about what learning and teaching digital making means to them and how it impacts their lives. So far, our community stories series has involved young creators, teachers, and mentors from the UK and US, India, Romania, and Ireland, who are all dedicated to making positive change in their corner of the world through getting creative with technology.
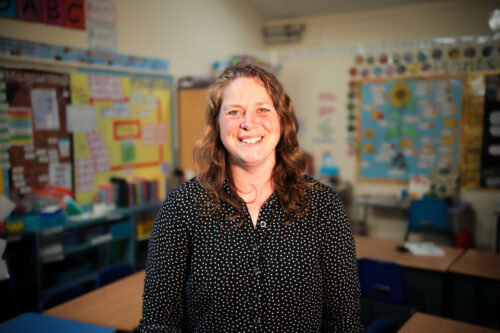
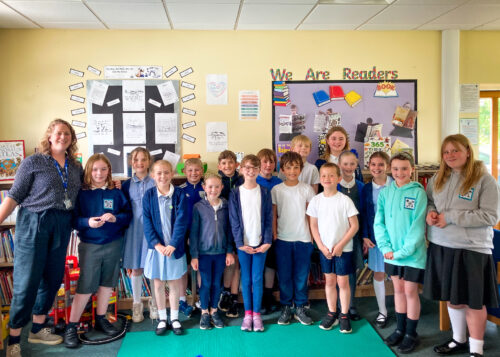
For our next story, we travel to a tiny school in North Yorkshire in the UK to meet teacher Sophie Hudson, who’s been running a Code Club since February 2021.
Introducing Sophie and Linton-on-Ouse Primary School
A teacher for 10 years, Sophie is always looking for new opportunities and ideas to inspire and encourage her learners. The school where she teaches, Linton-on-Ouse Primary School & Nursery in rural Yorkshire, is very small. With only five teachers supporting the children, any new activity has to be meticulously planned and scheduled. Sophie was also slightly nervous about setting up a Code Club because she doesn’t have a computer science background, sharing that “there’s always one subject that you feel less confident in.”
Sophie started the Code Club off small, with only a few learners. But then she grew it quickly, and now half of the learners in Key Stage 2 attend, and the club sessions have become a regular fixture in the school week.
“Once I did have a look at it [Code Club], it really wasn’t as scary as I thought. […] It has had a really positive influence on our school.”
Sophie Hudson, primary school teacher
Thanks to our free Code Club project guides and coding challenges like Astro Pi Mission Zero, Sophie’s Code Club has plenty of activities and resources for the children to learn to code with confidence — while having fun too. Sophie says: “I like the idea that the children can be imaginative: it’s play, but it’s learning at the same time. They might not even realise it.”
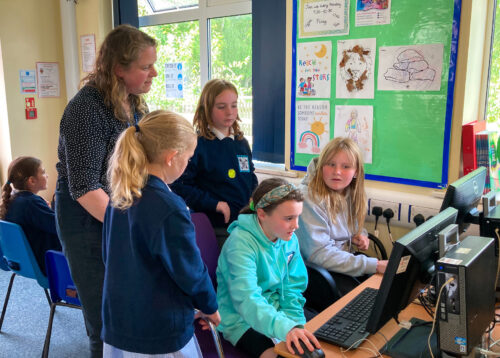
Sophie and some of her learners at Code Club.
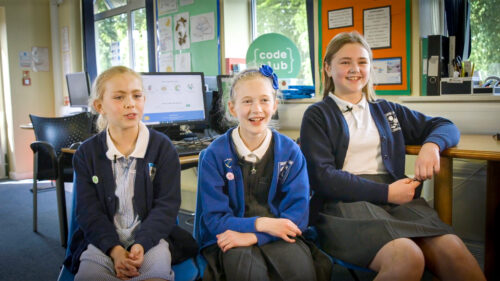
Visiting the Code Club at Linton-on-Ouse Primary School was a joyful experience. The children listened intently as Sophie kicked off the lunchtime club session. As they started to code, there were giggles and gasps throughout, and the classroom filled with sounds and intermittent squeaks from the ‘Stress ball’ project. It was clear how much enjoyment the learners felt, and how engaged everyone was with their coding projects. Learner Erin told us she likes Code Club because she can “have a little fun with it”. Learners Maise and Millie enjoy it because “it makes you worry less about getting stuff wrong, because you always know there’s a back-up plan.”
“It’s amazing. Anything is possible.”
Millie (10), learner at Sophie’s Code Club
Millie, Maisie and Fern from Sophie’s Code Club.
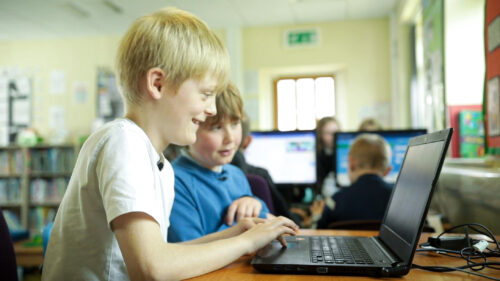
Attending Code Club had a profound impact on a 9-year-old learner called Archie, who shares that his confidence has improved since taking part in the sessions: “I would never, ever think of doing things that I do now in Code Club,” he says. His mum Jenni has also seen a difference in Archie since he joined Code Club, with his confidence improving generally at school.
Archie and a friend code together at Sophie’s Code Club.
The positive impact that Sophie has on Linton-on-Ouse Primary School & Nursery is undeniable, not only by running Code Club as an extracurricular activity but also by joint-leading science and leading PE, computing, and metacognition. Head teacher Davinia Pearson says, “How could you not be influenced by someone who’s just out there looking for the best for their class and children, and making a difference?”
Help us celebrate Sophie and her Code Club at Linton-on-Ouse Primary School & Nursery by sharing their story on Twitter, LinkedIn, and Facebook.
„Ще изградим свят без война и омраза!” Това заявиха лауреатите на Деветия международен литературен ученически конкурс „Който спаси един човешки живот, спасява цяла вселена” от сцената на Международния конгресен център…
Победата на едно поколение. Така много американски медии описаха решението на Върховния съд на САЩ за отмяна на конституционното право на аборт. Страната бе залята от множество протести на фона на доволството в консервативно-религиозните кръгове, които от десетилетия работят активно за премахването на „Роу срещу Уейд“. Под това име е известно съдебното решение от 1973 г., според което по Конституция всяка жена има право да реши дали да прекъсне бременността си.
Разделителните линии са добре познати – слабонаселеният Среден Запад и южните консервативни щати срещу Западния и Източния бряг, където са концентрирани икономическите и културните двигатели на страната; крайнорелигиозните активисти срещу умерените, атеистите, секуларистите. По последни данни белите евангелисти представляват най-голямата група, която смята, че абортите трябва да са незаконни в повечето или във всички случаи. В същото време 84% от нерелигиозните американци настояват правото на аборт да бъде запазено, както и 66% от чернокожите протестанти, 60% от белите протестанти и 56% от католиците.
В допълнение, само крайноконсервативните избиратели казват, че абортите трябва да са незаконни в повечето или във всички случаи; останалите три групи – умереноконсервативните, либералните и крайнолибералните избиратели – са на мнение, че правото на аборт трябва да е защитено. Иронично, на абортите се противопоставят онези възрастови групи, които са най-далеч от детеродна възраст – над 50-годишните, но дори и там надделяват хората, които подкрепят правото на аборт. Подкрепа, която преобладава сред американското общество и остава непроменена от края на 80-те до наши дни.
Защо тогава се стигна до това противоречиво решение на Върховния съд на САЩ?
Причините са комплексни, а процесите имат дълга история. Тя съчетава надигането на реакционерско движение в консервативните кръгове в САЩ вследствие на културните революции през 60-те години; изграждането и вкопаването на силно евангелистки лобита и групи за натиск в политиката; „конституционното разлагане“ на американската система; спада на доверие в науката и медицината вследствие на лоша комуникация между учени и държава; силно изродената здравна система; и не на последно място, враждебността към държавните институции като активна политика на крайните консерватори през последните три десетилетия.
Следващият въпрос съвсем естествено би бил:
Защо това трябва да интересува българите?
Както Светла Енчева писа още през 2019 г., и у нас наблюдаваме налагането на привнесени теми от американската културна война. Правото на аборт никога не е било тема в България, което не пречи на активисти като Александър Урумов, когото Енчева описва като „евангелист и небезизвестен борец срещу джендъра“, да публикуват текстове срещу абортите в своя блог. Този тип наратив върви активно във Facebook групи като РОД (Родители обединени за децата), тясно свързани с противопоставянето на важни социални политики в защита на децата.
В допълнение, Евангелската църква остава сред малкото институции, които активно работят с българската ромска общност, и то с нарастващо влияние. А руската пропаганда с радост експлоатира американския екстремизъм, който пасва на наратива за защита на „традиционните ценности“, като взаимовръзките между двете са описани още преди години. Затова и не е изненадващо, че силно проруската Българска православна църква и евангелската общност споделят едни и същи доктрини. И както показват скорошни политически събития и обрати, не е никак невъзможно те да повлияят на политиката.
Кой прави аборт?
След решението „Роу срещу Уейд“ през 1973 г. броят на абортите в САЩ нараства, но от средата на 80-те насам се наблюдава продължителен спад, като за 2019 г. са извършени 629 898 процедури. От тях 56% са хирургически и 44% медикаментозни, а от 1982 г. насам намалява и броят на клиниките, които предлагат този тип медицинска интервенция. Статистиката обаче не означава нищо, ако не предоставим контекста на причините, които карат една жена да вземе толкова тежко решение: данните от 2019 г. показват, че за мнозинството жени процедурата е за първи път и най-много са жените, които вече имат едно или повече деца – 60% от тези жени вече са майки. В 93% от случаите абортът се прави по време на първия триместър, или преди 13-тата гестационна седмица, и само 1% от абортите се правят след 21-вата седмица.
Най-изтъкваните причини за аборт са, че раждането на дете би попречило на образованието и работата на жената или на способността ѝ да се грижи за други хора, които зависят от нея (74%). Почти половината от запитаните жени казват, че правят аборт, защото не искат да бъдат самотни майки или защото имат проблеми с партньора си. Четири от десет жени вече имат достатъчно деца, а една трета от тях не са готови за дете. Грижата за други хора е фактор при по-възрастните жени, а неготовността да бъдат родители – при по-младите. Това означава, че ако проблемът с раждането на деца наистина трябва да бъде адресиран, то семейните консултации, ролята на бащата, платеното майчинство, финансовата помощ и подкрепата от работодателя, както и институции, които да подпомагат двойката (не само жената) при отглеждането на дете и грижите за други хора, трябва да бъдат основни цели на насърчаващата политика.
САЩ остават единствената развита държава в света без гарантирано платено майчинство, в сравнение с държави като Великобритания (39 седмици), Швеция (68 седмици), Естония (82 седмици) и Япония (минимум 52 седмици). Държавните инвестиции в ранна детска грижа също са на последните места от страните в развития свят. Съединените щати обаче се нареждат на първите места по усложнения и смърт по време на раждане, като цената на процедурата и отглеждането на дете е една от най-високите сред сходни икономики.
И все пак – спасяваме ли човешки живот?
Макар че крайноконсервативните кръгове твърдо се противопоставят на изброените по-горе социални политики (първият неоконсервативен президент Роналд Рейгън е известен с речите си срещу т.нар. welfare queens, или „кралиците на социалните помощи“), те настояват, че отхвърлянето на „Роу срещу Уейд“ е в името на спасяването на човешки живот. Както казахме по-горе, по-голямата част от абортите се извършват преди края на първия триместър. Науката не може да даде категоричен отговор кога един зародиш се превръща в човек. Това е въпрос, който се разисква от етиката посредством сложни аргументи – например достатъчна ли е биологичната активност, за да предположим съзнание?
Ако приемем религиозната постановка, че в момента на зачатието вече може да говорим за живот, тъй като оплодената яйцеклетка съдържа пълния генетичен материал на ембриона, който ще се развие до човек, то трябва да третираме всяка клетка в човешкото тяло по същия начин. Ако приемем, че трябва да има развитие на мозък и мозъчна дейност, сме изправени пред проблема, че само мозъчната активност не предполага наличието на съзнание, нито други присъщи на човешкото процеси и качества.
Поради това най-валидният извод е, че животът започва, когато плодът може да оцелее самостоятелно извън утробата, и именно тази постановка е началната точка за законодателството, което определя правото на аборт. Радикалната теория, третираща плода като правен субект, разглежда аборта като убийство, но от нея следва плодът да придобие правоспособност, включително например правото на издръжка от бащата от момента на зачеване.
Най-важният аргумент обаче остава сигурен и неоспорим: че майката вече е развита личност със свой живот и самостоятелно право на избор, поради това и насилственото износване и раждане се счита за нарушение на човешките права. Затова и майката трябва да бъде началната точка в преценката за законодателни мерки.
Защитниците на пълна или почти пълна забрана на абортите се прицелват в късните аборти (този 1% от всички процедури) именно поради гореизброените етични и биологични аргументи. Но и преди отхвърлянето на „Роу срещу Уейд“ 43 от общо 50 щата така или иначе забраняват късните аборти по причини извън медицинските. Ограниченията варират, но щати като Калифорния, Аризона и Ню Йорк например се позовават на момента, от който се смята, че плодът може да оцелее самостоятелно извън утробата. Аляска, Колорадо, Ню Хемпшир, Ню Джърси, Ню Мексико, Орегон и Върмонт са сред малкото щати, в които късните аборти са разрешени без ограничения.
Долу държавата, освен ако не става въпрос за личния ви живот
Законодателството в САЩ в такъв случай не се различава особено от европейското, където повечето държави ограничават процедурата до първия триместър, освен в случаите, когато е застрашен животът или здравето на майката – в такъв случай процедурата се прави и по-късно. Европейската практика приема, че силно ограничителното законодателство не взема предвид сложни и силно индивидуални медицински проблеми, генетични болести и малформации, както и усложнения по време на бременността. В малкото европейски изключения става въпрос за регрес от този тип практика поради религиозни причини, какъвто е случаят в Полша.
Парадоксът нараства, ако вземем предвид, че консервативните кръгове в САЩ са яростни адвокати на ограничаването на държавната намеса и изобщо на регулацията от какъвто и да било вид. Но това противоречие е привидно: съвременният американски консерватизъм отхвърля регулация на сектори от обществено значение – здравеопазване, околна среда, трудови правоотношения и икономика, – но е силно ориентиран към контролиране на личната сфера: право на аборт, достъп до контрацепция, сексуално образование, еднополови бракове и съжителство, по-скоро с оглед на морални и религиозни съображения, отколкото на съвременни научни или правни аргументи. С две думи, регулацията няма място в борбата за по-добро заплащане на труда или за единна здравна система, но с пълна сила може да влезе в спалнята ви. Някои права са по-важни от други.
Един от доводите на Върховния съд е, че „Роу срещу Уейд“ представлява прекомерен федерален контрол над щатите, чиито жители трябва сами да пишат законите си на щатско ниво чрез влияние над публичното мнение, лобиране, гласуване и кандидатиране за постове. Проблемът е, че демократичните механизми и системи, които подобно решение би обслужило, са проядени от порочни практики, а общественото доверие в тях е рекордно ниско. Същото важи и за доверието във Върховния съд.
След решението на Върховния съд регулацията на абортите става различна във всеки щат
Пример за крайност е Уисконсин, където след отмяната на прецедента „Роу срещу Уейд“ е върнат предишният закон за абортите отпреди 170 години. Този закон вероятно няма да бъде реформиран – отчасти и защото в законодателните органи доминират републиканците, които са разчертали електоралните граници така, че да гарантират спечелването на изборите. Върховният съд се контролира от същата партия и наскоро постанови, че именно тези манипулирани карти на избирателните райони трябва да се ползват като основа дори когато се чертаят нови.
Подобни практики не са запазена марка само на една партия, а нарастващата политическа поляризация влияе на недоверието във Върховния съд, което е сравнително нов феномен. Най-фрапантният случай от последните години е номинацията на Мерик Гарланд през 2016 г. от демократичния президент Барак Обама, която бе блокирана от републиканците, тъй като те настояваха, че не може да бъде избран нов съдия във Върховния съд в година на избори. Четири години по-късно идентична ситуация, но с обратен знак – номинацията на Ейми Кони-Барет от консервативния президент Доналд Тръмп мина безпроблемно. Поради тези и други фактори нараства подкрепата за реформа на Върховния съд, особено с оглед на възможността за оспорване на резултатите от президентските избори през 2024 г., което ще се реши именно на тази инстанция.
Дотогава обаче реалността е повече от мрачна за много американски жени, най-вече от малцинствата и от по-бедните прослойки на обществото. Законът в Алабама например забранява абортите изобщо, без изключения за изнасилване или кръвосмешение. В други щати, като Арканзас, абортите са забранени след 20-тата седмица, освен при случаите на изнасилване, кръвосмешение и заплаха за живота на майката, но по-сурови закони без подобни изключения вече са предложени и в момента са блокирани от федерални съдии, тоест предстоят евентуални промени. В Делауер законодателите вземат мерки още след встъпването в длъжност на президента Тръмп през 2017 г. и вписват правото на аборт в законодателството, като аборт не може да се извършва след момента, в който плодът би могъл да оцелее извън утробата. Подобна мозайка от сценарии не е по вкуса на крайноконсервативните активисти, чиято следваща вероятна стъпка е криминализирането на абортите на федерално ниво – въпреки аргументите, че всеки щат трябва да има свободата да пише своите закони.
Добрата новина: демократичните механизми в САЩ все още работят достатъчно добре, че крайното законодателство наистина да бъде подложено на изпитание от съдии и прокурори, както и от групи за натиск извън правната система, в политиката. Лошата: когато религиозният фундаментализъм успее да се намеси в политиката и да измести научната експертност и правните аргументи, пред нацията се открива дълъг път на конфронтация с истината: забраната на абортите не намалява абортите, но убива жени. Разбира се, ако жените са държавна собственост, а не човешки същества със свобода на избор и преценка, това вероятно не е от чак толкова голямо значение.
Резултатите от националното външно оценяване (НВО) на учениците и тази година разпалиха обществени страсти. Докато едни акцентират върху нещата, които децата, държащи изпитите за външно оценяване, не знаят, не разбират или не могат, други обръщат внимание на проблемите в училищното образование, част от които се явява и НВО. По какъв начин училището изгражда знания и умения и с адекватен инструментариум ли се оценяват те? Бива ли да свеждаме седмокласниците единствено до формалните резултати, които постигат на изпити и на базата на които успяват или не успяват да се класират за „елитна“ гимназия?
По отношение на инструментариума за оценяване два случая станаха обект на критики.
След като от Министерството на образованието и науката разпространиха информация, че четвъртокласниците не могат да обяснят какво е пожарникар, стана ясно, че проблемът е в изпитния критерий, според който децата на 10–11 години трябва непременно да се сетят, че става въпрос не просто за гасене на пожари, а за професия. Дори да оставим настрана, че при нивото на институционална и гражданска култура у нас дори възрастни се затрудняват да разграничат човека от различните му социални роли, критерият не е коректен и във фактологическо отношение – има и пожарникари, които са доброволци.
Вторият случай е с разказа „Талисманът“ на варненеца Красимир Бочев, даден за преразказ на изпита по литература след VII клас. Обект на критики стана както посредствеността на самото произведение, така и избирането на точно този автор, който е последовател на „Възраждане“ и споделя конспиративни теории за COVID-19 и по всякакви други теми. В своя защита от МОН отговориха, че художествените качества на разказа не влизат в критериите за избор на произведение, а най-важното е той да е лесен за преразказване. От това е логично да се заключи, че възпитаването на литературен вкус не е сред приоритетите на обучението по литература.
Ала по-сериозният проблем е в самата философия на училищното образование –
инструментариумът и критериите са малка част от нея. След излизането на резултатите от НВО за седми клас Надежда Цекулова от БХК и педиатърката Бояна Петкова публикуваха постове във Facebook, в които подлагат на критика системата на училищното образование. Система, която изтезава и децата, и родителите им. Която създава училища за отличници и образователни гета. В която стойността на 13–14-годишните тийнейджъри (и способностите на родителите им) се измерва според получените точки на изпитите, които пък предопределят по-нататъшния им живот.
Образователната система е фиксирана върху постиженията и класациите не само в България, макар у нас допълнителни проблеми да са неадекватните учебни програми и критерии, както и огромното образователно неравенство. В германската федерална провинция Бавария например бъдещето на учениците се предопределя дори по-рано – едва в пети клас се решава кое дете е „достойно“ за гимназия, в края на която ще може да държи матура, и за кое е по-добре да отиде в професионално училище. А без матура няма университет. Възможно е човек да стигне до нея и вече като възрастен, но трябва да има много силен мотив да надскочи професионалната си среда.
Нека си представим, че може да бъде и друго.
За да се научите да карате колело или кънки, задължително е да преодолеете страха си от падане. Основен принцип в съвременното обучение по чужди езици е, че за да проговори на новия език, човек не трябва да се бои да прави грешки. Като се замислим, така е с всичко, което учим – страхът да не сбъркаме блокира както разбирането, така и свободното прилагане на наученото. Когато основният мотив е оценяването, на практика не се учим, а се приспособяваме към определени критерии за оценка.
Да помечтаем, че в училище няма оценки. Че целта на училищното образование е учениците да се развият като личности, които разбират света, в който живеят, и са способни да се ориентират в него. Уроците са интересни и децата виждат какъв е смисълът да научат едно или друго. Не живеят в непрекъснат стрес да не се „провалят“, а експериментират и си помагат взаимно. По-големите ученици избират кое в какъв обем и с каква сложност да изучават според интересите си, стига да съберат определен брой „точки“. Няма „елитни“ и гетоизирани училища, а навсякъде може да се получи образование с аналогично качество.
Как тогава ще се влиза в университет?
За разлика от училището, в университета (поне на теория, макар с масовизирането на висшите училища ситуацията да не е точно такава) се спазват високи академични стандарти. Ето защо е логично достъпът до него да става след проверка на потенциала за усвояването на такива стандарти, тоест след изпит. И е важно висшето образование да съдържа по-високи изисквания за качество. Още повече че то (отново на теория) е предназначено за хора, които са мотивирани и знаят какво искат. Не съществува обаче никаква необходимост входът към него да е следствие от резултатите в училище. Освен всичко човек може да реши да се насочи към университет и в зряла възраст, когато вече е забравил какво стои зад оценките от гимназиалната му диплома.
По същия начин и хората, които се насочват към професия след училище, не следва да са заложници на образователните си успехи или провали, особено ако тези успехи или провали нямат пряка връзка с това, което ще се изисква от тях в работата. Често се получава така, че дори човек да е специализирал в определено професионално направление по време на образованието си, новата работа да изисква от него компетентности, които не е изучавал и тепърва трябва да усвоява. Това се случва впрочем нерядко и на хора, завършили университет.
Утопия, но не съвсем.
Така описаната картина не съществува в чист вид в никоя държава, но на много места може да намерим нейни елементи. Има висши училища, които приемат и без диплома за средно образование. Във финландските училища например оценките се формират по съвсем други критерии и нямат добре познатата ни санкционираща функция. Принцип на образованието по Монтесори е да няма оценки и домашни, а процесът на обучение прилича по-скоро на игра. В някои училища и образователни системи по-големите ученици сами избират какъв да бъде учебният им план, на кое да наблегнат повече и на кое – по-малко.
Контрапродуктивността в съвременни условия на училището, което е изградено според принципите на дисциплината и санкциите, адекватни на демократичните общества до втората половина на ХХ век, се забелязва от философи и експерти в областта на образованието. Сред тях са например немските философи Рихард Давид Прехт и Харалд Леш, за чиято книга „Как образованието сполучва“ вече писахме в „Тоест“.
Въпросът е защо моделите на несанкциониращо училище не се превръщат в масова практика.
Проблемът е не толкова в закостенялостта на самото образование, колкото в спецификите на социалната система, чиито неравенства образованието възпроизвежда, ако се позовем на френския социолог Пиер Бурдийо. В представата, че светът едва ли не ще се срути, ако хората не научат още от деца къде им е мястото. В инерцията да се произвеждат не личности, а винтчета в машината, които стават безполезни, когато тя бъде заменена от нова. В илюзията, че училищната месомелачка е „подготовка за живота“.
Обикновено детството се описва като „щастливо“ и „безгрижно“. Това клише трябва да е произведено от хора, които са забравили какво е да си дете. Или поне какво е да си ученик. Със стреса на ученическия живот може да се сравни само стресът на отдадения родител на ученик. И пак не е сигурно кой е по-стресиран, защото за ученика всичко се случва за първи път и съответно се преживява драматично. Към децата в училищна възраст има безброй изисквания, а в същото време те нямат правото да се разпореждат с живота си. Но пък могат да провалят бъдещето си – или поне да го направят много по-трудно, защото са блокирали на някой изпит.
„Знам, че не може, но може ли да може?“,
пеят босненците от „Дубиоза колектив“. Вероятно една радикална реформа на училищното образование, в която се премахнат оценките, няма да е безпроблемна. От друга страна, проблемите на настоящото училищно статукво сме свикнали да приемаме за даденост, едва ли не като природен факт. Но в степента, в която осъзнаваме, че може да бъде и друго, има и надежда за промяна.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.



 Pratik Patel is a Sr Technical Account Manager and streaming analytics specialist. He works with AWS customers and provides ongoing support and technical guidance to help plan and build solutions using best practices and proactively helps in keeping customer’s AWS environments operationally healthy.
 Structure the narrative
 Resize and stabilize the commits
 Explain the context