What are the proposed benefits? The primary motivation behind
“Fedora Verified” is to build trust-based recognition that grants
elevated, privileged rights within the project. Most notably, this
status would determine eligibility for strategic governance
activities, such as:
Voting in Fedora community elections.
Running for leadership or decision-making roles within the project
(i.e., Fedora Council, FESCo, Mindshare Committee, EPEL Steering
Committee).
(Potential, unplanned) Accessing specific shared project resources
or educational opportunities (e.g., Red Hat training credits).
The blog post includes a list of proposed baseline metrics for
“Verified” status as well as open questions to be decided. A survey
on the topic will be open until May 5.
This post is cowritten with Avdhesh Paliwal from Oldcastle.
Oldcastle APG is one of the largest suppliers of construction materials in North America, including asphalt and concrete. The company also provides construction and paving services across more than 150 facilities. As the company migrated from on-premises systems to Infor Cloud ERP hosted on Amazon Web Services (AWS), they faced a critical challenge: maintaining the real-time operational reporting capabilities that hundreds of users across customer service, finance, logistics, and manufacturing depended on daily.
This post explores how Oldcastle used AWS services to transform their analytics and AI capabilities by integrating Infor ERP with Amazon Aurora and Amazon Quick Sight. We discuss how they overcame the limitations of traditional cloud ERP reporting to deploy real-time dashboards and build a scalable analytics system. This practical, enterprise-grade approach offers a blueprint that organizations can adapt when extending ERP capabilities with cloud-native analytics and AI.
Challenges with cloud ERP reporting
The primary challenge that we faced was finding a solution that could accomplish the following:
Maintain real-time data access – Our on-premises environment supported hundreds of complex real-time reports, but Infor ERP Cloud’s configuration-based reporting covered minimal reports of our operational needs.
Support complex reporting requirements – Users needed multi-dimensional analysis across customer service, finance, logistics, and manufacturing functions.
Provide seamless user experience – Business users demanded integrated reporting within the ERP network without switching between multiple systems.
Enable advanced analytics –We needed capabilities for demand forecasting, machine learning (ML) capabilities, and intelligent search across real-time data.
Scale efficiently – The solution needed to support over 100 concurrent users and process millions of transactions while maintaining performance.
Expose Data using API – The solution needed to expose data through APIs, allowing both external and internal applications to access and consume the data securely and efficiently.
Our existing batch reporting process created significant operational challenges across our organization. We had to wait for batch reports, which consumed valuable time and led to delays in critical decision-making across many of our teams. This lag prevented us from capitalizing on real-time business insights and responding quickly to operational issues or economic changes. Without immediate data visibility, our managers couldn’t make timely, data-driven decisions, resulting in missed opportunities for improvement and competitive advantage. Our IT team also struggled with constant report requests but lacked a scalable system to deliver them efficiently, further compounding the productivity loss across our organization.
Solution overview
AWS Solutions Architects worked closely with our application team to build a comprehensive analytics and AI solution to address these challenges. The architecture uses Infor Data Fabric Stream Pipelines to deliver real-time data to AWS. It powers operational dashboards, artificial intelligence and machine learning (AI/ML) models, and intelligent search capabilities. This approach aligns with Infor’s broader strategy of integrating ERP data, data lake information, machine learning (ML) predictions, and documentation to provide comprehensive end-to-end business solutions.
Real-time data streaming architecture
The foundation of our solution is Infor’s Data Fabric Stream Pipelines, an add-on feature that provides real-time streaming data processing. When data events are ingested into Data Fabric, Stream Pipelines processes them immediately and continuously without waiting for storage in the data lake. This approach minimizes the data journey and accelerates operations, helping us extract insights from our data in real time.
The end-to-end workflow consists of the following components:
Data ingestion – Infor Data Fabric tables stream changes in real-time. We enabled Stream Pipelines as an add-on feature within our Infor Cloud ERP environment. We Configure the specific ERP table that we want to stream (such as sales orders, inventory, financial transactions) to publish change events immediately upon data modification. Stream Pipelines captures insert, update, and delete operations with metadata about the operation type and timestamp.
Load distribution – Because Infor can’t reach our private VPC directly, we use Elastic Load Balancing (ELB) to distribute traffic and provide secure database access. We implemented a Network Load Balancer (NLB) with static Elastic IP addresses in public subnets, giving us stable, allowlisted IP addresses for Infor’s outbound connections. We configured an Amazon Relational Database Service (Amazon RDS) router with Amazon Elastic Compute Cloud (Amazon EC2) instances as NLB targets. These routers forward traffic from the NLB to our Amazon Aurora database in the private subnet using iptables NAT rules. This makes sure that even if the IP of Aurora changes during failover, our static Elastic IPs remain constant. We configured security groups to accept HTTPS traffic (port 443) only from Infor’s IP ranges on the NLB and allow traffic only from the NLB to the RDS routers.
Connection management – We use Amazon RDS Proxy to manage database connections and provide automatic failover. We deployed RDS Proxy in the private subnet between our RDS router instances and Aurora cluster to pool and reuse connections. This is critical for handling our high-frequency streaming data. We configured the proxy with IAM authentication for secure credentials and set connection pool parameters based on our expected concurrent stream volume to handle burst traffic without overwhelming the database. With automatic failover enabled, if our primary Aurora instance fails, RDS Proxy automatically redirects traffic to the promoted replica, maintaining continuous data flow.
Data storage – We store our operational data in Amazon Aurora PostgreSQL- Compatible Edition with multi-Availability Zone deployment for high availability. We provisioned an Aurora PostgreSQL cluster with one writer instance and multiple reader instances across different Availability Zones. We designed our database schema to handle the incoming streaming data, storing it in JSONB columns for flexible querying while using the native JSON functions of Aurora PostgreSQL when we need to parse and normalize specific fields. We created indexes on frequently queried fields to maintain query performance as our data volume grows. We also configured automated backups with point-in-time recovery and set up the automatic storage of Aurora scaling to accommodate our data growth.
Analytics and visualization – Amazon Quick Sight delivers the interactive dashboards and pixel-perfect reports our teams need. We created a Quick Sight account and established a connection to our Aurora PostgreSQL database using VPC connectivity with credentials stored in AWS Secrets Manager. We identified which datasets benefit from SPICE (Super-fast, Parallel, In-memory Calculation Engine) caching—typically aggregated or frequently accessed data—and configured incremental refresh schedules to keep them current. We built our dashboards using the visual interface of Quick Sight, using calculated fields for business logic, parameters for user interactivity, and row-level security rules to make sure that users only see data that they’re authorized to access. For pixel-perfect reports, we use the pixel-perfect report feature of Quick Sight to create formatted documents suitable for printing or regulatory compliance.
Embedded integration – We securely embedded Amazon Quick Sight dashboards within Infor OS through Amazon API Gateway, which generates dynamic URLs for seamless user access. We enabled Quick Sight embedding in our AWS account and registered our Infor domain. We created an API Gateway REST API with Lambda functions that authenticate users, validate Infor session tokens, and call QuickSight’s GenerateEmbedUrlForRegisteredUser API to produce time-limited, signed URLs with row-level security. Our Lambda function maps Infor user roles to Quick Sight permissions and applies dashboard filters based on the user’s organizational context. We configured CORS settings in API Gateway to allow requests from our Infor domain and implemented rate limiting. On the Infor side, we embedded the Quick Sight dashboards using iframe elements that call our API Gateway endpoint, providing a seamless experience where our users access analytics without leaving the ERP interface.
The following diagram illustrates the real-time analytics architecture:
This embedded experience aligns with Infor’s broader system strategy of integrating insights seamlessly into workflows.
Results and business impact
The implementation using this architecture on AWS brought substantial benefits, directly addressing the critical challenges that we faced and demonstrating measurable value in employee productivity and core business process optimization.
Business process improvement
The solution successfully addressed Oldcastle’s key operational challenges:
Challenge: Limited visibility into real-time operations
– Solution delivered: Deployed over 50 complex dashboards and reports in eight months, providing immediate visibility across customer service, finance, logistics, and manufacturing.- Technical achievement: Used Infor Data Fabric Stream Pipelines to process data events immediately upon ingestion, alleviating delays from traditional batch processing.- Impact: Real-time streaming architecture using the NDJSON format makes sure decision-makers have access to current operational data when they need it most.
Challenge: Fragmented user experience requiring multiple systems
– Solution delivered: Dashboards embedded directly into the Infor environment through Amazon API Gateway.- Technical achievement: Generated dynamic URLs for secure embedding with single sign-on capabilities.- Impact: Users access insights without leaving their familiar interface, with personalized views based on roles and permissions that maintain context across the application.
Challenge: Inflexible reporting limiting business agility
– Solution delivered: Both interactive dashboards and pixel-perfect reports are available to meet diverse business needs.- Technical achievement: Quick Sight SPICE caching enables subsecond response times on complex analytics across large datasets.- Impact: On-demand access for immediate insights, scheduled distribution, custom formatting aligned with corporate standards, and multiple export formats (PDF, CSV, Excel).
Challenge: Delayed decision-making due to outdated data
– Solution delivered: Real-time visibility into operations enabled faster, data-driven decisions.- Technical achievement: The Multi-AZ deployment of Amazon Aurora PostgreSQL maintains high availability and continuous data access.- Impact: Decision-makers can respond immediately to operational issues and economic changes with current, reliable data.
Scalability and performance
The architecture delivered exceptional scale and performance, addressing concerns about future growth: – High concurrency: Supports over 100 concurrent users without performance degradation- Data volume handling: Processes millions of transactions daily in real-time- Elastic scaling: Aurora read replicas automatically scale based on demand- Future-ready: Architecture designed to expand to additional regions and use cases- Cost efficiency: AWS services avoided complex third-party integrations, with infrastructure costs scaling efficiently with business growth- API capabilities: Ability to expose data using AWS technologies enables integration with third-party and internal applications
Conclusion
Our journey proves that cloud ERP migrations don’t require sacrificing real-time operational reporting capabilities. By combining Infor Data Fabric Stream Pipelines with AWS analytics and AI services, we’ve maintained real-time data access, accelerated innovation, improved user experience, and built a system that scales efficiently as our business needs evolve. The combination of Infor’s enterprise-grade ERP system with the comprehensive analytics capabilities of AWS has given us the best of both worlds. As we expand our AWS analytics and AI capabilities, we’re not just maintaining parity with on-premises systems, we’re unlocking new sources of business value that weren’t possible before.
Further reading
For more information on the services mentioned in the post, see the following resources:
AWS services:
Amazon Aurora PostgreSQL Features – Learn more about the high-availability database that powers Oldcastle’s real-time data storage and Multi-AZ deployment strategy
Amazon Quick Sight Embedded Analytics – Explore how to embed interactive dashboards and pixel-perfect reports directly into your enterprise applications, as demonstrated in Oldcastle’s Infor OS integration
Amazon Bedrock for Generative AI – Discover opportunities to enhance your analytics system with AI-powered insights and intelligent search capabilities
Elastic Load Balancing – Understand how to distribute traffic and secure database connections when integrating cloud ERP systems with AWS services
Amazon API Gateway – Learn how to create secure, dynamic URLs for embedding analytics and exposing data through APIs to internal and external applications
Infor Resources:
Infor Data Fabric Documentation – Deep dive into Stream Pipelines configuration and real-time data streaming capabilities that enable immediate operational insights
In the first part of Configure a custom domain name for your Amazon MSK cluster, we discussed about why custom domain names are important and provided details on how to configure a custom domain name in Amazon MSK when using SASL_SCRAM authentication. In this post, we discuss how to configure a custom domain name in Amazon MSK when using IAM authentication. We recommend you read the first part of this blog as it captures solution details implementation steps.
Solution overview
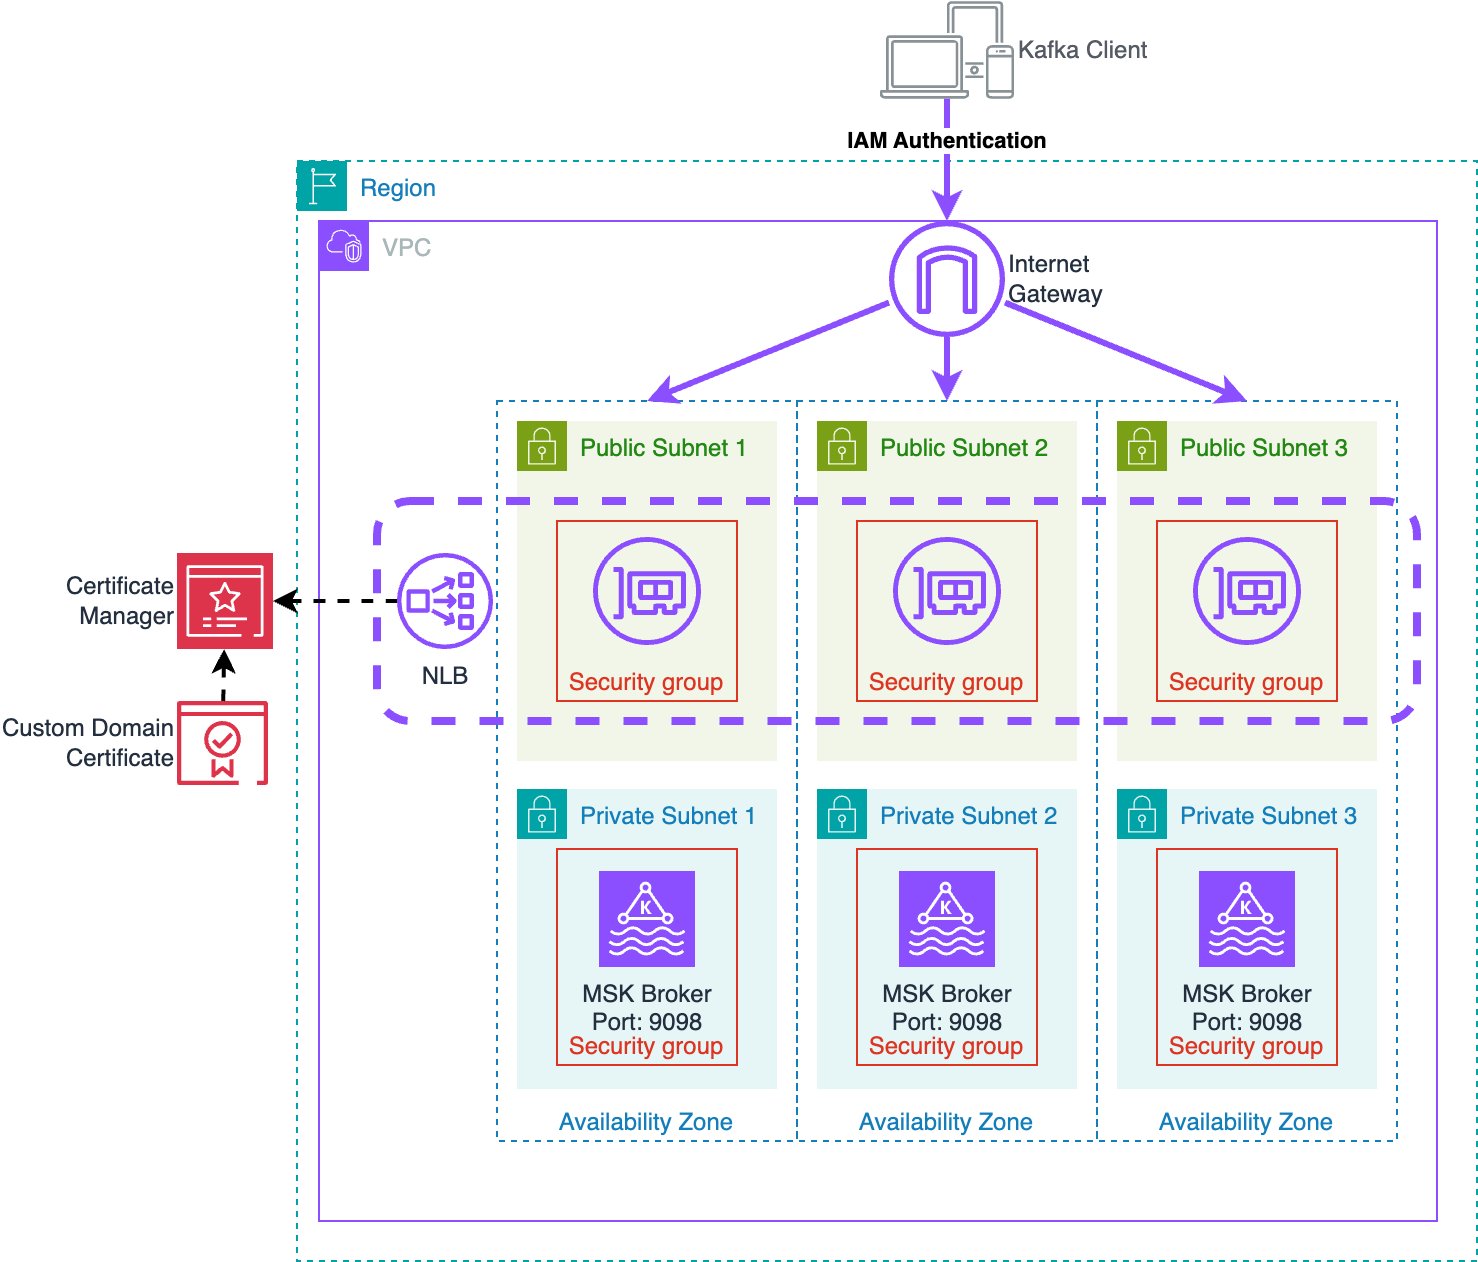
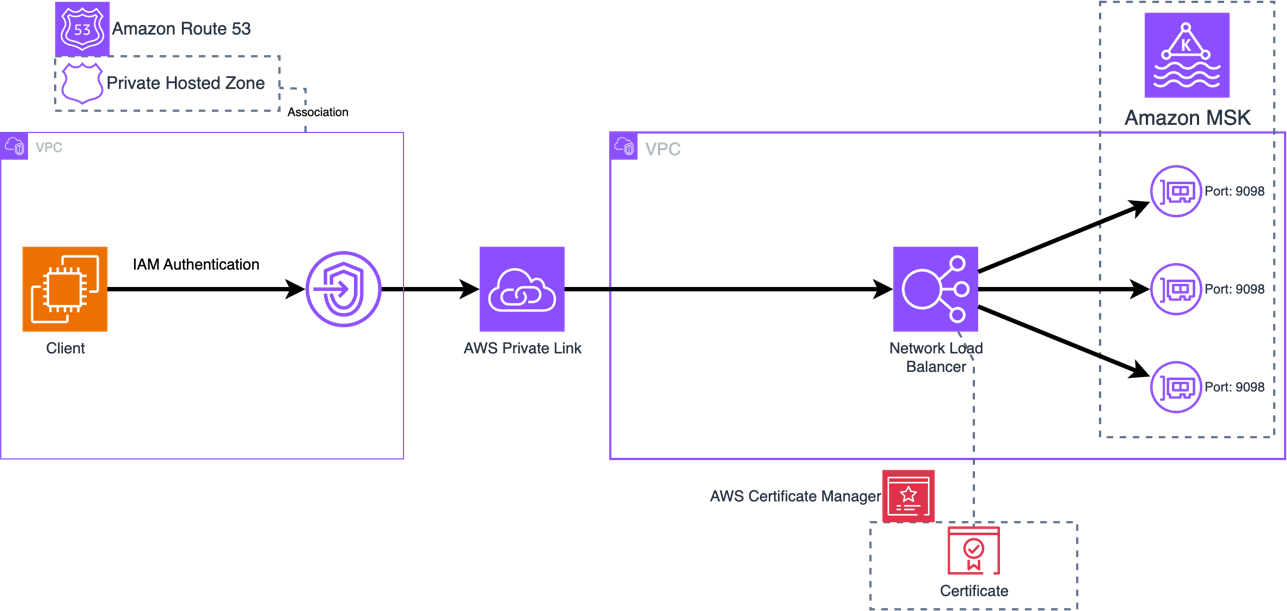
IAM authentication for Amazon MSK uses TLS to encrypt the Kafka protocol traffic between the client and Kafka broker. To use a custom domain name, the Kafka broker needs to present a server certificate that matches the custom domain name. To achieve this, this solution uses an Network Load Balancers (NLBs) with Amazon Certificate Manager to provide a custom certificate on behalf of the MSK brokers, and a Route 53 Private Hosted Zone to provide DNS for the custom domain name.
The following diagram shows all components used by the solution.
Certificate management
For clients to perform TLS communication with the MSK cluster the cluster needs to provide a certificate with hostnames matching the custom domain name. This solution uses a certificate in AWS Certificate Manager (ACM) signed with a Private Certificate Authority (PCA) for TLS with the custom domain name. This solution uses a certificate with bootstrap.example.com as the Common Name (CN) so that the certificate is valid for the bootstrap address, and Subject Alternative Names (SANs) are set for all broker DNS names (such as b-1.example.com). Since this solution uses a private certificate authority, the CA chain must be imported into the client trust stores.
This solution works with any server certificate, whether certificates are signed by a public or private Certificate Authority (CA). You can import existing certificates into ACM to be used with this solution. Certificates must provide a common name and/or subject alternative names that match the bootstrap DNS address as well as the individual broker DNS addresses. If the certificate is issued by a private CA, clients need to import the root and intermediate CA certificates to the client trust store. If the certificate is issued by a public CA, the root and intermediate CA certificates will be in the default trust store.
Network Load Balancer
The NLB provides the ability to use a TLS listener. The ACM certificate is associated with the listeners and enables TLS negotiation between the client and the NLB. The NLB performs a separate TLS negotiation between itself and the MSK brokers. In addition to the above architecture, this solution also allows using AWS Private Link to connect the cluster to external VPCs. This allows secure access to MSK between VPCs while using a custom domain name.
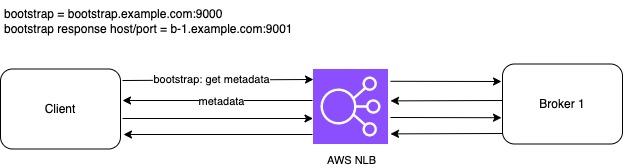
The following diagram illustrates the NLB port and target configuration. A TLS listener with port 9000 is used for bootstrap connections with all MSK brokers set as targets. IAM authentication is configured to run on port 9098 of the MSK brokers using a TLS target type. A TLS listener port is used to represent each broker in the MSK cluster. In this post, there are three brokers in the MSK cluster starting with port 9001, representing broker 1 and up to port 9003, representing broker 3.
Domain Name System (DNS)
For the client to resolve DNS queries for the custom domain, we use an Amazon Route 53private hosted zone to host the DNS records, and associate it with the client’s VPC to enable DNS resolution from the Route 53 VPC resolver. This solution uses a private MSK cluster and private DNS. For publicly accessible MSK clusters a public NLB and DNS provider such as a Route53 public hosted zone can be used.
Amazon MSK
Finally, each broker needs to have its advertised listeners configuration (advertised.listeners) updated to match the custom domain name and NLB ports. Advertised listeners is a configuration option used by Kafka clients to connect to the brokers. By default, an advertised listener is not set. Once set, Kafka clients use the advertised listener instead of listeners to obtain the connection information for brokers. MSK brokers use the listener configuration to tell clients the DNS names and ports to use to connect to the individual brokers for each authentication type enabled. Advertised listeners are unique to each broker; and the cluster won’t start if multiple brokers have the same advertised listener address. For this reason, this solution uses a unique custom DNS name for each broker (such as, b-1.example.com).
Solution Deployment
To deploy the solution, use the CloudFormation template from the GitHub repository.
This template deploys a VPC, NLB, PCA, ACM certificate, MSK cluster, and an Amazon EC2 instance for cluster connectivity. The EC2 instance includes a script to handle updating the broker advertised.listeners settings to match the custom domain name. For more information on deploying a CloudFormation template, refer to Create a stack from the CloudFormation console.
After deploying the CloudFormation template, run the script to update advertised listeners as follows:
Retrieve the MSKClusterARN and CertificateAuthorityARN from the CloudFormation outputs for your stack as they will be used in subsequent steps.
Navigate to the EC2 console and identify the KafkaClientInstance. Choose Connect to connect to the instance using AWS Systems Manager Session Manager.
Session Manager starts a session in shell. Start a bash session with the command:
bash -l
The Kafka client SDKs have already been installed in the EC2 instance. You can update the advertised.listeners configuration as follows, replacing CLUSTER_ARN with the ARN of your MSK cluster retrieved from CloudFormation in step 1:
Note that once this script completes, the brokers will have new advertised listeners configurations. Connections using the standard IAM address for the MSK service will not work until we complete the next steps, as the brokers will redirect connections over this address back to the custom domain name and TLS will fail.
Next, we need to create a truststore with the certificate for our AWS Private Certificate Authority (PCA) to allow TLS with the NLB. In the following command, replace PCA_ARN with the ARN of the PCA retrieved from CloudFormation in step 1: We’re using the default Java truststore which uses the password changeit.When asked “Trust this certificate?” enter “yes”.
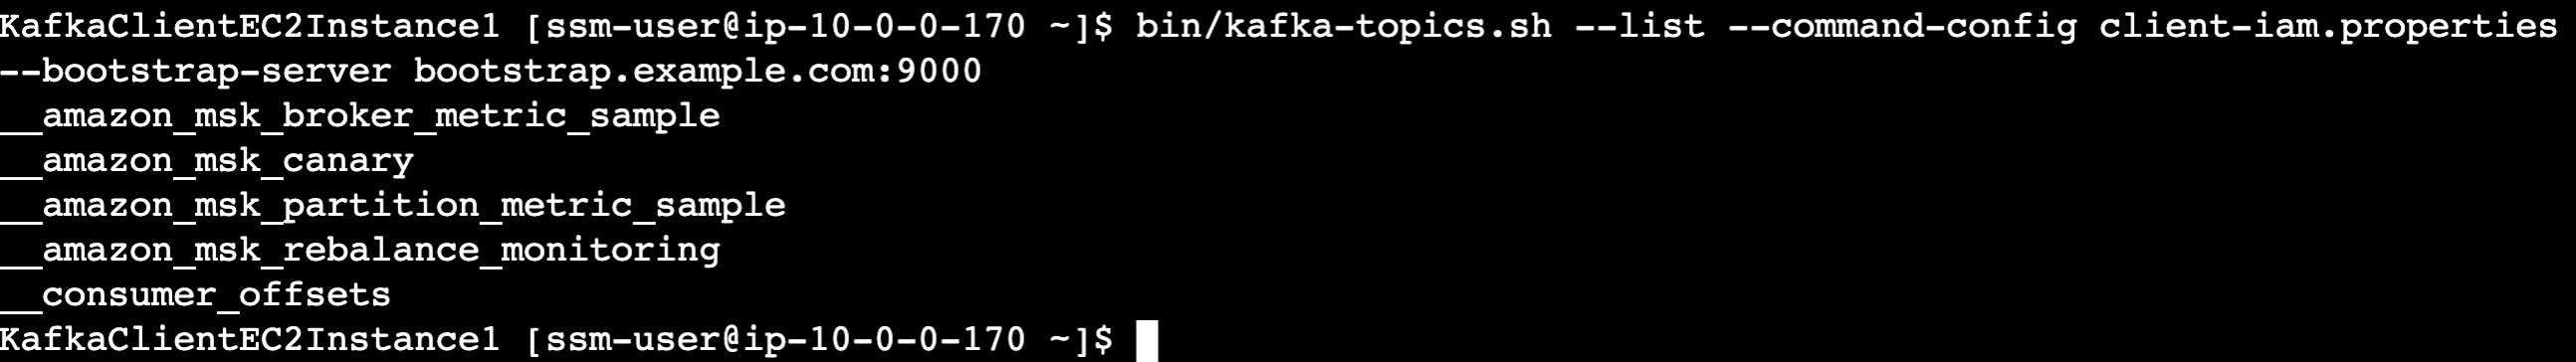
Verify you can connect to the cluster using IAM authentication using our new custom domain name, replacing bootstrap.example.com with your own custom domain name if you used a different one in CloudFormation:
To stop incurring costs navigate to CloudFormation and delete the CloudFormation stack to remove all resources provisioned by CloudFormation.
Frequently Asked Question about Custom Domain Name
Customers have asked a few questions about implementing custom domain names with MSK. You can find answers to some of the most popular questions here.
Are there any limitations for this solution on MSK?
The advertised.listeners setting was removed as a dynamic broker in KRaft-based Kafka clusters. Therefore, this solution is only supported in Zookeeper-based MSK clusters. Additionally, this solution is only applicable to SASL/SCRAM and IAM-authentication based MSK clusters.
How the custom domain name solution scales when we add new brokers?
For TLS, if using Subject Alternative Name (SAN) to list individual broker DNS hostnames, you will need to create a new certificate that includes the names of the additional brokers. One option is to create a certificate with SANs for more brokers than needed to allow for growth.If a wildcard certificate is used, you do not need to modify certificates when adding brokers.
What changes are required when we remove brokers?
Amazon MSK supports scale-in by removing brokers from the cluster. Brokers are removed from each availability zones (AZ). So a 6 broker Amazon MSK cluster deployed in 3 AZ can be reduced to 3 broker cluster deployed in 3 AZ. When brokers are removed, you can remove the NLB listeners for the removed broker along with the Route53 DNS endpoints. However, you can also leave them as is, or just remove the target IP from the broker numbers target group. The NLB will mark the targets as unhealthy and stop directing traffic to them. If you ever plan to scale-out the number of brokers, you can re-use the existing NLB listeners and Route 53 DNS entries and would only need to update the target IPs used in the broker numbers target group.
Is there any change in configuration required if there is any broker failure?
No. When a broker fails, Amazon MSK replaces the failed broker with a new broker instance keeping the configuration of the broker exactly the same. So, there would be no change in the advertised listener of the broker. Once the broker is healthy, the broker can accept new connections and read/write traffic.
Can you use Amazon MSK Replicator between MSK clusters in multiple AWS Regions when using the custom domain name solution?
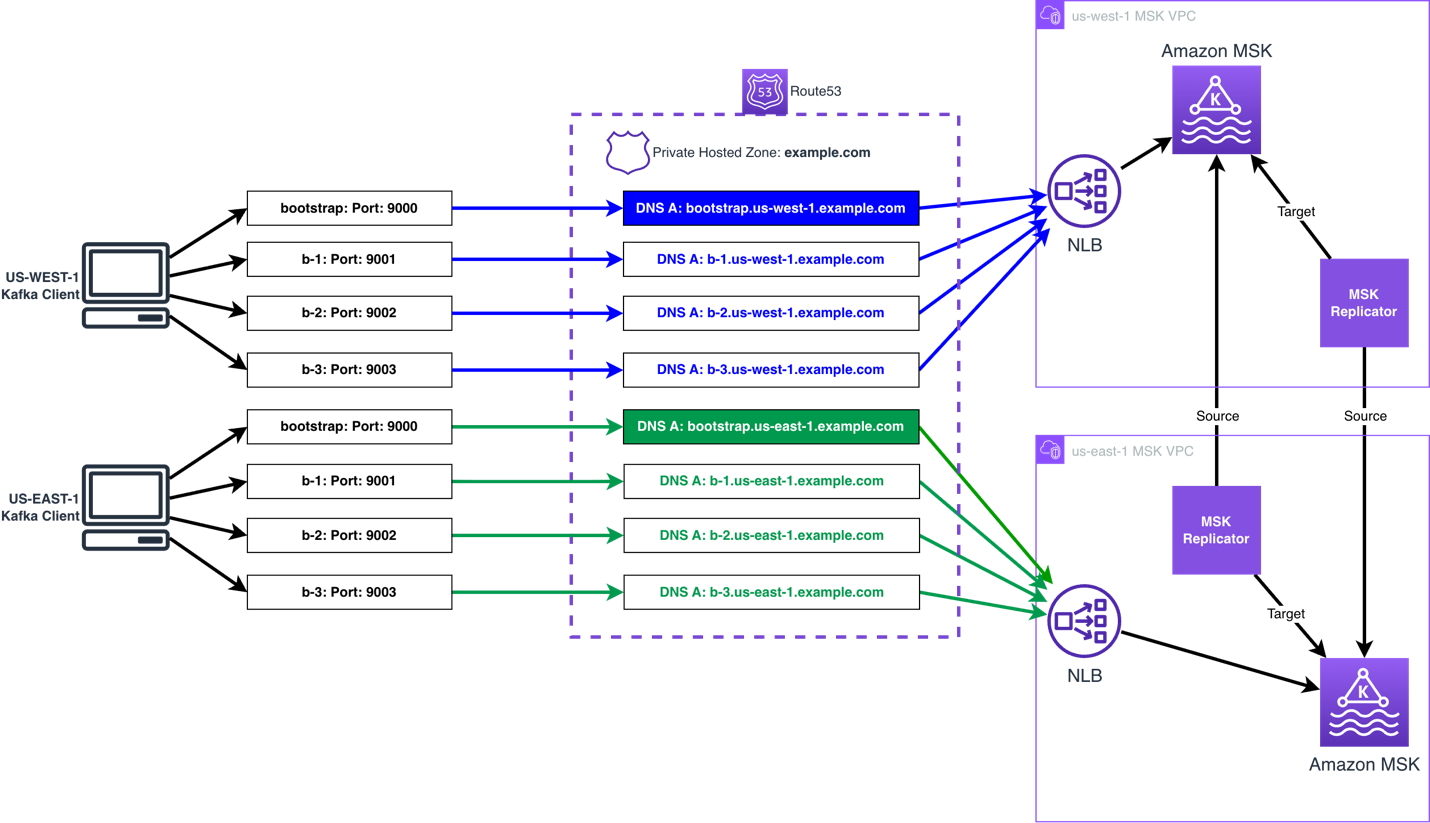
The Amazon MSK Replicator can be used when using the custom domain name solution, either in an active-passive or active-active setup. The same process can be followed to set the custom domain name.
The following diagram shows an active-active AWS multi-Region MSK setup using the custom domain name solution:
Can I use a global bootstrap DNS name to connect to Amazon MSK clusters deployed across multiple AWS regions when IAM authentication is enabled?
No, it is not possible to use a global bootstrap reference to represent MSK clusters deployed in multiple AWS Regions, unless the client is aware of the cluster’s region when connecting. To use IAM authentication, the correct AWS Region must be included in the IAM authentication request for a given cluster. This is because the AWS Region is a part of the Sigv4 authentication protocol used by IAM. This scope prevents the IAM authorization being used to talk to a resource in another AWS Region. You can provide the AWS Region in one of two ways– with region-specific bootstrap URLs or by explicitly configuring the region.
For example, if the bootstrap string is bootstrap.us-east-1.example.com, then msk-iam-auth library will to extract the AWS Region from the broker connection string and use us-east-1 in its IAM requests. If the bootstrap string is simply bootstrap.example.com, then the client must explicitly configure AWS_REGION=us-east-1 to connect to the cluster if it is in us-east-1, or us-west-2 if it is in us-west-2.
Note that this is a limitation for IAM authentication, but not for SASL/SCRAM authentication. With SASL/SCRAM authentication, if the client’s credentials are applied to both clusters the global endpoint can point to either cluster and the client will be able to connect. The AWS Region is not used in SASL/SCRAM authentication, so it does not restrict the authentication scope.
How to allow public access to a private MSK cluster using the custom domain name solution?
To provide public access to a MSK cluster using the custom domain solution, you will need to do the following:
Create an Internet-facing NLB, and associate public subnets (subnets that have a route to the Internet Gateway attached to the VPC).
Create ingress rules in both the NLB and MSK security groups permitting the required public addresses. Note: the port will be 9098 for the MSK security group, and the ports you are using on the NLB listeners.
Provide public DNS resolution for the Kafka clients, by using a Route 53 public zone, or an alternative public DNS resolver.
The client needs have IAM credentials, with permission, to talk to the MSK brokers, using an IAM role, IAM access keys, IAM Roles Anywhere, or another mechanism that uses the AWS Security Token Service (AWS STS) to create and provide trusted users with temporary security credentials.
In the first part of the blog, two patterns have been highlighted. How to decide which pattern to use and why?
Option 1: Only bootstrap connection through NLB
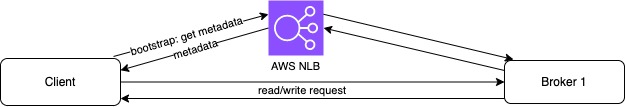
If the Kafka clients have direct access to the broker, then you can use custom domain name for the bootstrap connection while the clients can still connect to the MSK Brokers with broker DNS. This is the simplest option, as it does not require custom TLS certificates or TLS listeners.Note that this option is not necessary when using MSK Express brokers, as MSK Express brokers already manages bootstrapping via a broker-agnostic connection string. For MSK Express, this option does not add value other than configuring a custom domain name for appearances / simplicity of client configuration. For MSK Standard brokers, this can improve client connectivity by making connection strings broker agnostic.
Option 2: All connections through NLB
When Kafka clients don’t have direct access to Amazon MSK Brokers, routing all connections through the NLB can be preferred. This can occur when a client is deployed in a different VPC than Amazon MSK VPC or the client is external, and when Amazon MSK Multi VPC Connectivity is not an option. In general, Amazon MSK Multi VPC Connectivity is preferred as this is a simpler pattern for most organizations to manage MSK Connectivity across accounts and VPCs.When Multi VPC Connectivity is not an option, NLB can be used to provide connectivity with Transit Gateway or PrivateLink, and the solution mentioned in the blog should be used.
Here is an example architecture how Kafka client and Amazon MSK cluster deployed in two separate VPCs but connected via AWS Private Link.
Is Amazon Route 53 required to use a custom domain name with Amazon MSK?
You can use an alternative DNS resolver service, and do not require Amazon Route 53 to use a custom domain name with Amazon MSK. The only requirement is that your clients can resolve against your DNS resolver service. The only change required, is to use a CNAME for the DNS records, referencing the NLBs DNS record, in place of the Alias records, as this is record type is only available in Amazon Route 53.
We don’t use Amazon Certificate Manager (ACM), can NLB integrate with other 3rd party certificate managers?
NLB only supports ACM to bind a certificate to a TLS listener. You can import a certificate created using your 3rd party certificate manager into ACM, and do not need to create a certificate using ACM.
Getting connection to node terminated during authentication after setting advertised.listeners , what could be the issue?
As the issue started to occur after changing the advertised.listeners configuration, the issue is unlikely to be related to permissions. The following can cause this issue:
The NLB and/or client’s Security Group does not permit access to the listener ports on the NLB from the client.
A firewall appliance between the NLB and client does not permit the client to talk to the NLB using the listener ports.
The advertised.listeners configuration has an error causing the client to receive invalid details, such as a typo in the name. If this is the case, use a client in the same VPC as the MSK broker that has IAM permissions to talk to the MSK broker, and Security Group rules permitting connectivity, you then use the following command to delete the advertised.listeners configuration.
BROKERS_AMAZON_DNS_NAME such as b-1.clustername.xxxxxx.yy.kafka.region.amazonaws.com:9098.
Getting “unexpected broker id, expected 2 or empty string, but received 1”, what is causing this error?
This error is typically presented when the advertised.listeners configuration for one of the brokers has the port used by another broker set. For example broker 2 has port 9001 set for IAM, but this port is used to connect to broker 1, so broker 1 is responding with an error to say you presented broker id 2, but I am broker 1.
To correct this, you will need to update the broker with the incorrect advertised.listeners configuration to use the correct port. To gain access to the broker to make the change, you will need to use the following command to delete the incorrect configuration:
BROKERS_AMAZON_DNS_NAME such as b-2.clustername.xxxxxx.yy.kafka.region.amazonaws.com:9098.
You then need to use the following command to set the advertised.listeners configuration for that broker:
Note: The advertised.listeners configuration in the below assumes only IAM is used for authentication. If you are using additional authentication options, you will need to include them.
In this post, we explained how you can use an NLB, Route 53, and the advertised listener configuration option in Amazon MSK to support custom domain names with MSK clusters when using IAM authentication. You can use this solution to keep your existing Kafka bootstrap DNS name and reduce or remove the need to change client applications because of a migration, recovery process, or to use a DNS name in line with your organization’s naming convention (for example, msk.prod.example.com).
Try the solution out for yourself, and leave your questions and feedback in the comments section.
Благодаря на всички, гласували за ППДБ и особено на тези 13528, гласували за мен с преференция в София и още 1305 в Бургас. Ценим тази подкрепа и разбираме отговорността, която идва с нея.
Коалицията има ръст на гласовете с 62 хиляди и е единственият от субектите в предходния парламент, който има значим нетен прираст на гласове.
Но този резултат не е успех. Не е успех, защото хората не припознаха нас като годен субект да поеме управлението на страната.
И причините за това трябва да търсим в себе си. Нужно е да анализираме внимателно грешките и да предприемем корективни действия. Да отчетем проблемите в кампанията (разнопосочните послания, липсата на кохерентност на слогани, цветове, програми), за да сме в адекватна организационна форма, която да дава убедителна заявка за управление.
В парламента ще са налице 160 гласа, с които да бъде избран нов Висш съдебен съвет и съответно главен прокурор. С това не свършва демонтирането на модела, но е ключова стъпка, без която не може.
Още веднъж благодаря на избирателите за доверието. Ще действаме стриктно съгласно предизборните си ангажименти.
The open-source world is currently awash in
reports of LLM-discovered bugs and vulnerabilities, which makes for a lot more
work for maintainers, but many of the current crop are being reported
responsibly with an eye toward minimizing that impact. A recent report
on an effort to systematically find bugs in Python extensions
written in C has followed that approach. Hobbyist Daniel Diniz used Claude
Code to find more than 500 bugs of various sorts across nearly a million
lines of code in 44 extensions; he has been working with maintainers to get
fixes upstream and his methodology serves as a great example of how to keep
the human in the loop—and the maintainers out of burnout—when employing LLMs.
For executive leadership, the emergence of Kyber ransomware represents a significant and immediate threat due to its specialized, dual-platform deployment capability targeting mission-critical virtualization infrastructure (VMware ESXi) and core Windows file systems. This cross-platform approach, coupled with effective anti-recovery measures, drastically elevates the risk of a total operational disruption. Organizations should treat Kyber not merely as another ransomware strain, but as a specialized tool capable of causing a complete operational blackout. Recent real-world incidents have demonstrated that this approach can result in large-scale operational impact across enterprise environments.
During a March 2026 incident response engagement, Rapid7 recovered two Kyber ransomware payloads deployed in the same environment, one targeting VMware ESXi infrastructure and the other Windows file servers. This provided a rare opportunity to analyze both variants side by side. In March 2026, Rapid7 recorded over 900 ransomware incidents being publicly reported.
The ESXi variant is specifically built for VMware environments, with capabilities for datastore encryption, optional virtual machine termination, and defacement of management interfaces. The Windows variant, written in Rust, includes a self-described “experimental” feature for targeting Hyper-V.
Despite these differences, both samples share a campaign identifier and Tor-based ransom infrastructure, confirming coordinated cross-platform deployment. Notably, the ransomware’s cryptographic claims are not consistent across variants. The ESXi sample advertises “post-quantum” encryption using Kyber1024, but in practice relies on ChaCha8 with RSA-4096 key wrapping, while the Windows variant does implement the advertised hybrid scheme. As usual, ransom notes prove to be more aspirational than accurate.
Kyber is a relatively new ransomware group that has recently gained visibility. Despite this, public technical analysis of the malware remains limited. The lack of spotlight on the group presented an opportunity to share our findings with the community.
Technical analysis
Kyber is a cross-platform ransomware family targeting Linux/ESXi and Windows environments. Both variants share Tor infrastructure and a campaign ID, but differ in programming language they are written, crypto, and features. While both reference the same encryption scheme in their ransom notes, only the Windows variant appears to implement it as described.
Property
ELF (Linux/ESXi)
PE (Windows)
Language
C++, GCC 4.4.7 (2012)
Rust, MSVC 19.36 / VS2022
Actual crypto
ChaCha + RSA-4096
AES-256-CTR + Kyber1024 + X25519
Note claims
AES + X25519 + Kyber
AES + X25519 + Kyber
Extension
.xhsyw
.#~~~
Ransom note
readme.txt
READ_ME_NOW.txt
VM targeting
Native esxcli
PowerShell Get-VM (experimental)
Anti-recovery
None
11 commands (elevation required)
⠀
In addition, both variants share a common campaign ID and Tor-based infrastructure, including a negotiation portal and leak site, indicating coordinated operations across platforms.
Campaign ID: 5176[REDACTED]
Tor chat: Mlnmlnnrdhcaddwll4zqvfd2vyqsgtgj473gjoehwna2v4sizdukheyd[.]onion
Tor blog: Kyblogtz6k3jtxnjjvluee5ec4g3zcnvyvbgsnq5thumphmqidkt7xid[.]onion
Chat path: /chat/5176[REDACTED]
Linux/ESXi variant
The Linux/ESXi variant SHA-256: 6ccacb7567b6c0bd2ca8e68ff59d5ef21e8f47fc1af70d4d88a421f1fc5280fcis a 64-bit ELF executable, not stripped, written in C++ and statically linked against OpenSSL 1.0.1e-fips.
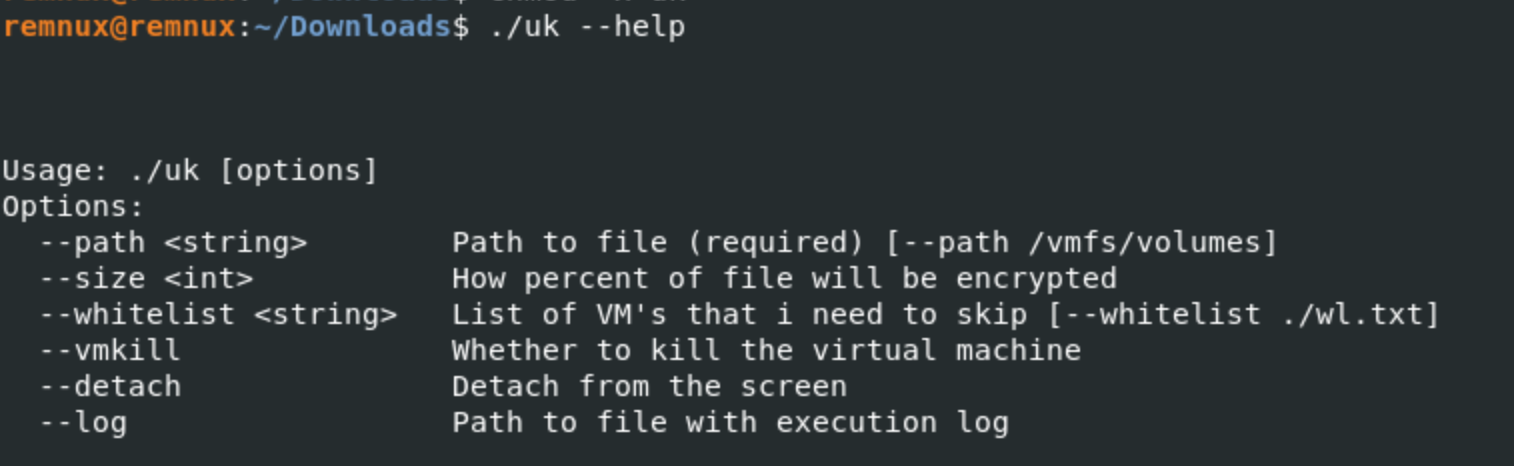
The sample was developed to target ESXi environments. As shown in Figure 2, the help text for the required path argument explicitly references the datastore path /vmfs/volumes, the root directory in VMware ESXi hosts where VMFS (Virtual Machine File System) datastores are mounted. The malware also relies on ESXi-native tooling esxcli and targets VMware-specific paths and artifacts.
Figure 1: The binary’s help text names /vmfs/volumes as the intended target path.
To ensure encryption continues after an SSH session ends, the malware implements a detach flag. When enabled, it forks and exits the parent process, allowing the child to run in the background. The child then calls setsid() to detach from the controlling terminal, avoiding the SIGHUP signal typically sent when a session closes.
This allows the attacker to disconnect safely while encryption of /vmfs/volumes datastores continues uninterrupted in the background.
Targeting VMware
If the vmkill flag is set, the binary enumerates all running VMs before starting encryption. It forks a child process that executes the ESXi-native management command esxcli vm process list, redirecting its output to a temporary file via dup2(). The output is then parsed line by line to extract Display Name and World ID pairs.
If a whitelist is provided via the whitelist argument, matching VMs are skipped. All other VMs are terminated sequentially using esxcli vm process kill type=softworld-id <id>, with the parent process waiting for each shutdown to complete before proceeding.
Two implementation choices stand out here. First, the ransomware uses fork/execlp rather than system(). By calling fork() and then execlp() directly, ransomware developers bypass the shell entirely. This means the arguments are passed as a null-terminated array of strings (argv) directly to the execve system call. If a VM name contained a space or a special character, a system() call might crash or behave unexpectedly, but execlp ensures the command is executed exactly as intended. This suggests the developer is familiar with low-level system programming.
Second, the use of type=soft requests a graceful shutdown rather than a forced termination. This likely reduces the risk of corrupting VM disk state prior to encryption. After issuing shutdown commands, the binary sleeps briefly for about ~2 seconds before continuing, allowing ESXi to complete the operation.
Directory traversal
The malware performs a recursive directory walk to identify targets. Interestingly enough, it drops a readme.txt ransom note into every folder before the encryption routine begins. The traversal logic does not follow symbolic links, as traversing them can lead to unexpected areas of the filesystem. The sample does not implement an extension allowlist. Files are encrypted unless explicitly excluded.
The binary explicitly ignores files with the following extensions or names:
Figure 2: Confirmed exclusion list from protecting in-progress files, already-encrypted files, and VMware system files from double-processing.
⠀
Encryption: marketing vs reality
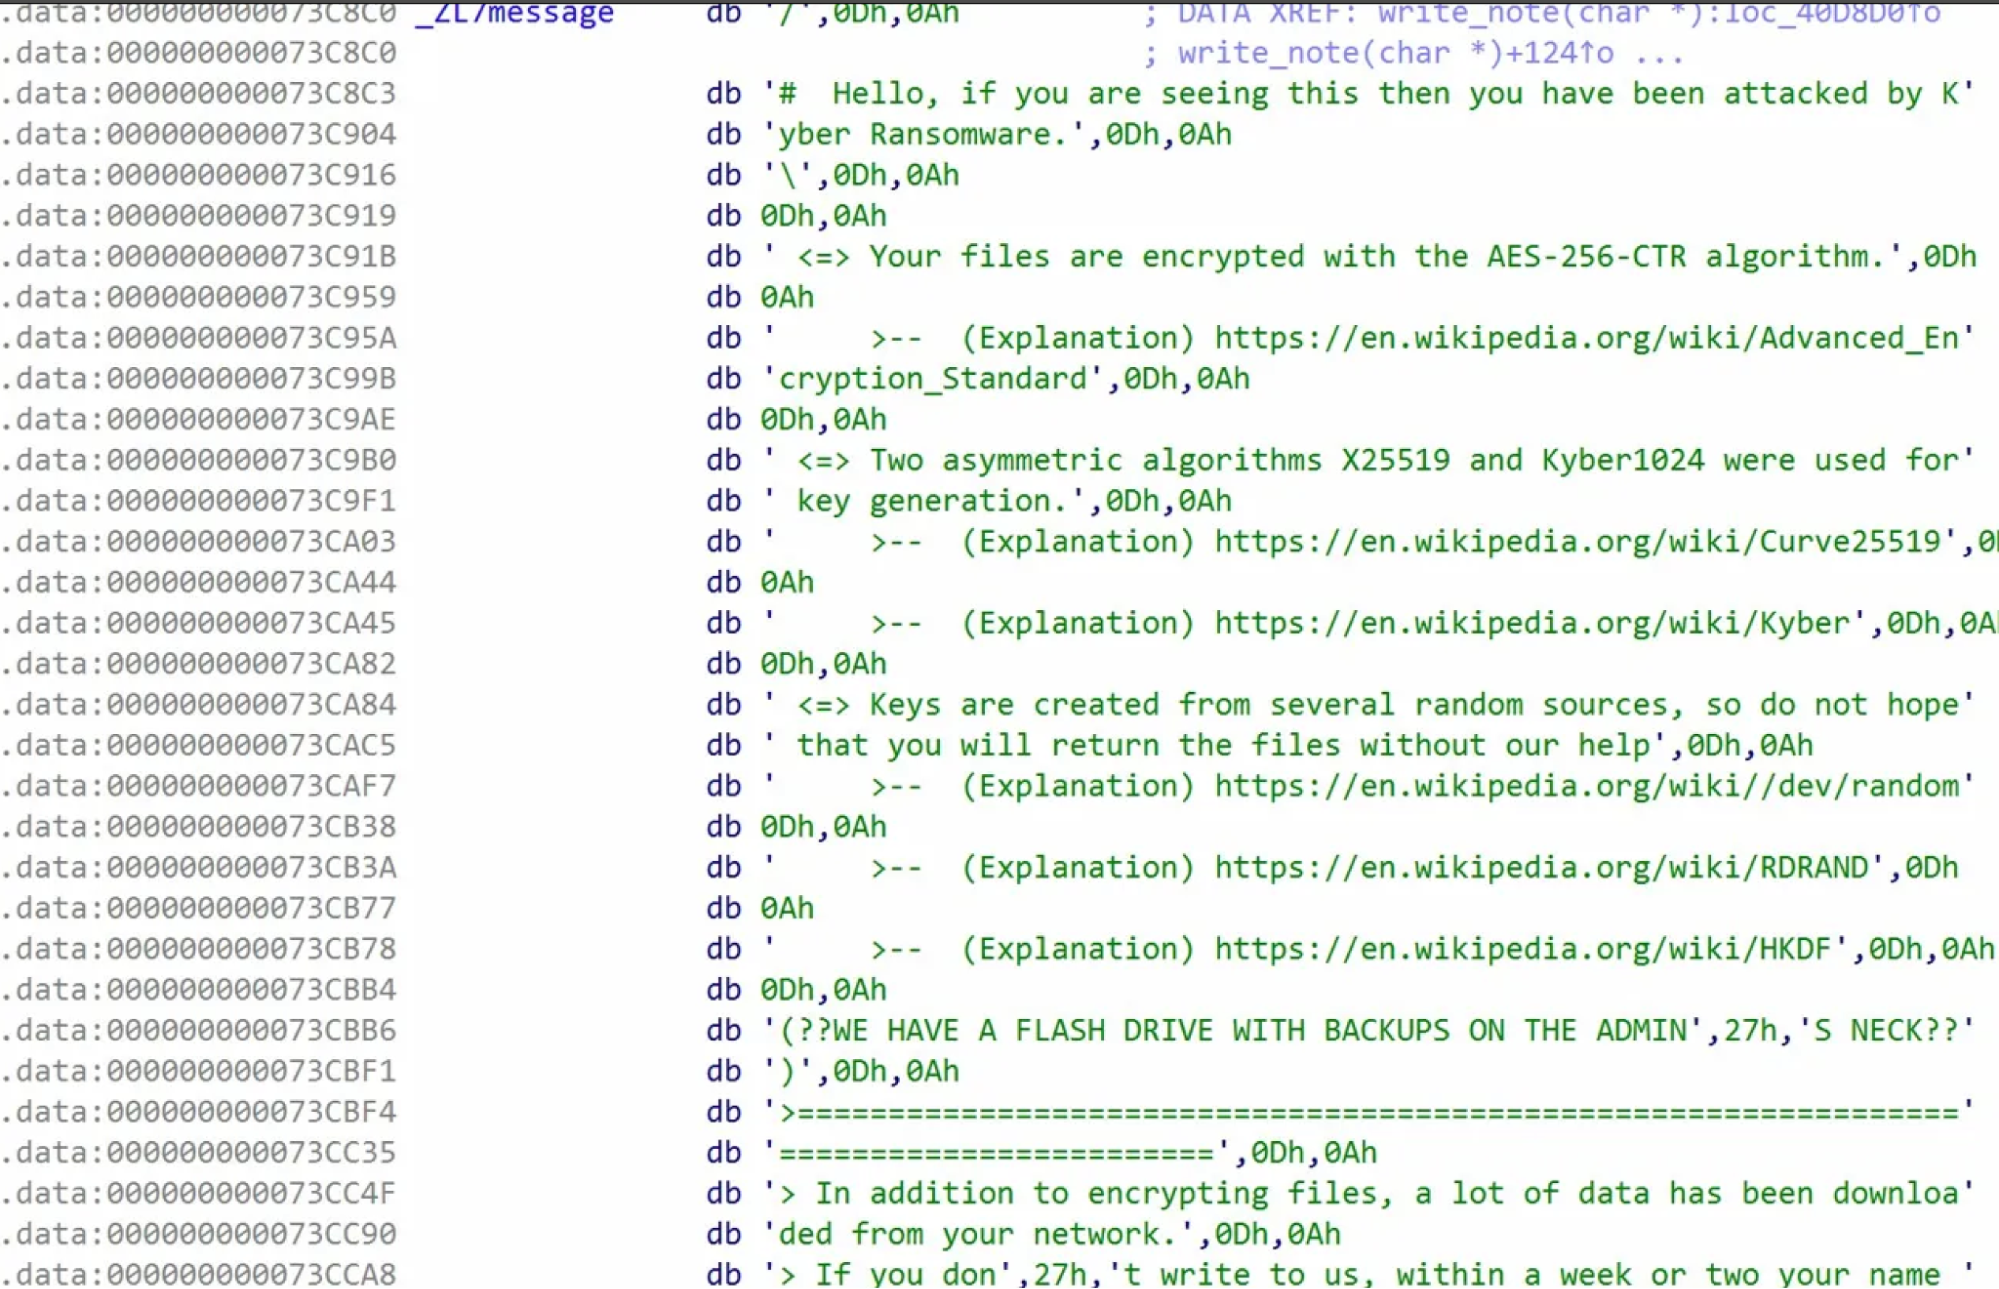
The ransom note claims that for encryption it uses AES-256-CTR, X25519 and Kyber1024 algorithms.
Figure 3: Ransom note embedded in the ELF binaries claims AES-256-CTR and X25519/Kyber1024 algorithms.
⠀
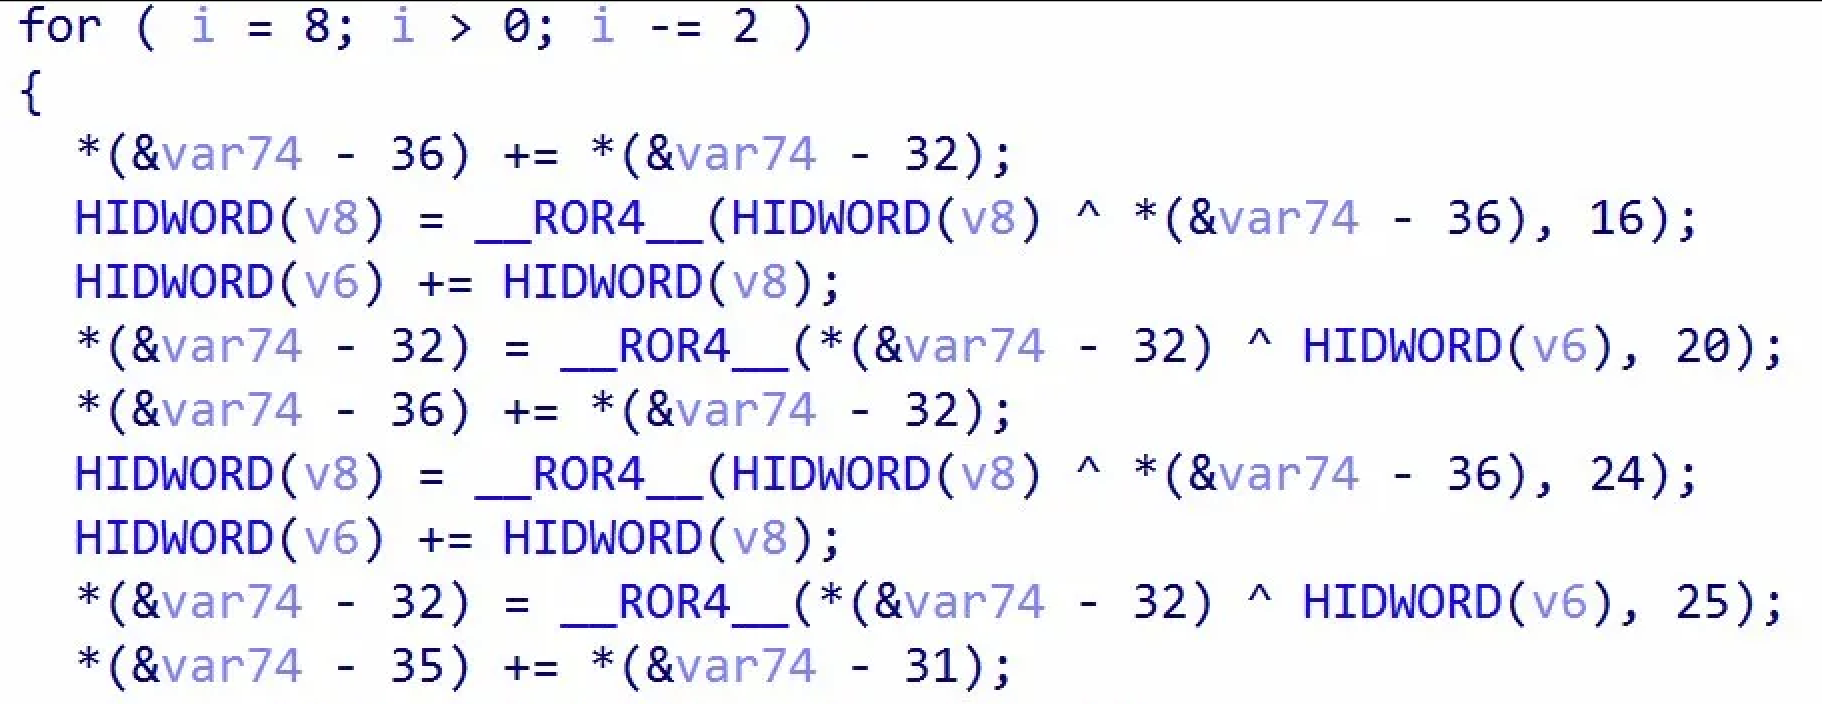
Our technical analysis, however, says otherwise. Decompilation of the core encryption logic shows the cipher is actually ChaCha8. Two indicators support this conclusion. First, in the ECRYPT_encrypt_bytes subroutine (Figure 5) the loop executes 8 rounds (i = 8; i > 0; i -= 2), and the code applies 32-bit right rotations with constants 16, 20, 24, and 25. These correspond to the standard ChaCha left-rotation constants (16, 12, 8, and 7) defined in RFC 8439.
⠀
Figure 4: IDA decompilation of ECRYPT_encrypt_bytes function
⠀
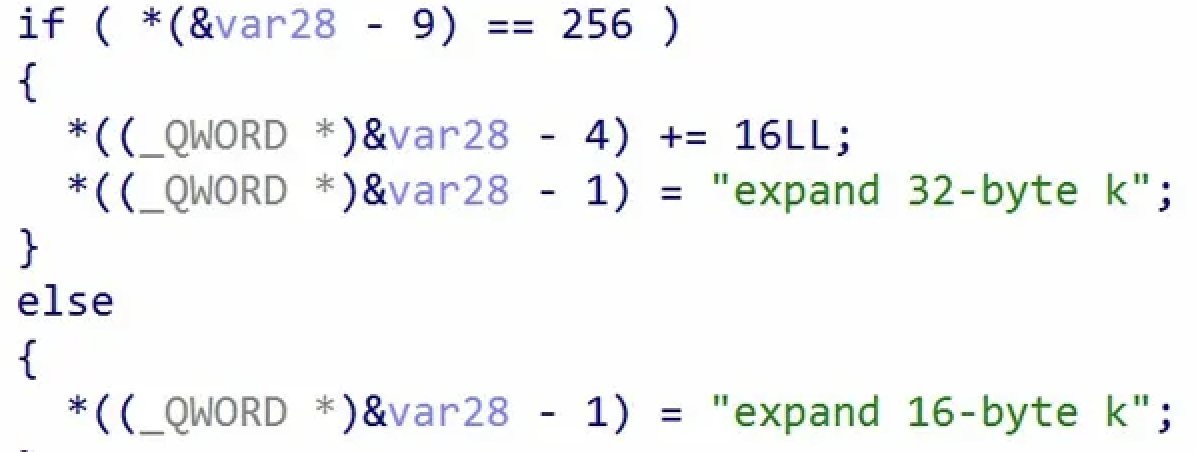
Second, the ECRYPT_keysetup function (Figure 6) uses the “expand 32-byte k” sigma constant. For 256-bit keys, the malware initializes its state by placing this constant in words 0–3 and the key in words 4–11 — mirroring the standard ChaCha layout.
⠀
Figure 5: IDA decompilation of ECRYPT_keysetup function
⠀
OpenSSL is statically linked but only handles RSA-4096 key wrapping. We did not find any “post-quantum”. The operator likely just copy-pasted the ransom note from a Windows variant that actually supports Kyber1024.
Partial encryption strategy
Partial encryption logic is size-based encryptFilePartly() function.
Files under 1MB: entire file encrypted
Files between 1MB and 4MB: first 1MB encrypted
Files above 4 MB: only a calculated portion of each file is encrypted, with the proportion controlled by size; the program validates this value as 0–100 in main(), and the default observed setting is 10.
This approach significantly reduces encryption time while still rendering large files (e.g., VMDKs) unusable.
Encryption workflow
Each file is encrypted with a unique ChaCha8 key. Before encrypting the file, the binary creates a .locksignal file and renames the original to .processing to prevent concurrency. It then checks the last 535 bytes for a metadata trailer containing the markers KYBER, CDTA, and ATDC. If these are present, the file is skipped as already encrypted.
For new targets, the malware generates a 40-byte key/IV set and wraps it using an embedded RSA-4096 public key. This metadata is appended to the file and verified before encryption begins. A redundant copy is also saved as <file>.cryptdata_backup. Encryption is performed in-place in 1 MB chunks. On success, the file is renamed from .processing to .xhsyw. Any files left with the .processing suffix indicate an interrupted or failed encryption attempt.
Defacing every entry point
Even before encryption, ransomware binary replaces three specific files:
SSH Access replaces /etc/motd (Message of the Day), displaying the ransom note immediately to anyone logging in via SSH.
Web Management replaces the VMware web UI index pages at both /usr/lib/vmware/hostd/docroot/index.html and the Host Client interface at /usr/lib/vmware/hostd/docroot/ui/index.html.
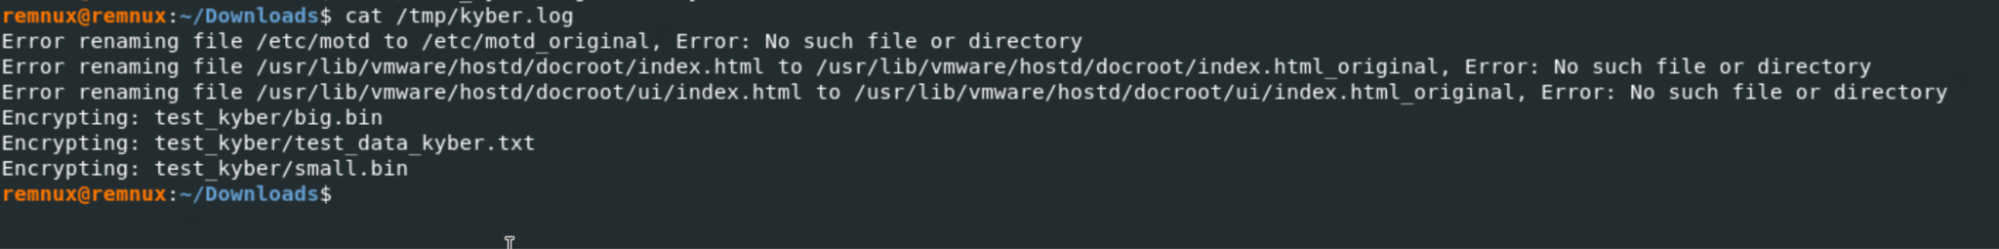
Whether an administrator logs in via SSH or hits the web management portal, they are immediately met with the ransom note. On non-ESXi systems where these paths don’t exist, the rename fails gracefully and execution continues.
Figure 6: Execution log from REMnux test: defacement fails gracefully on non-ESXi, encryption proceeds.
⠀
Windows variant
The Windows sample SHA-256: 45bff0df2c408b3f589aed984cc331b617021ecbea57171dac719b5f545f5e8d is a 64-bit PE executable written in Rust and compiled with MSVC (VS2022). Much like the ESXi variant, the Windows binary as well is not packed, obfuscated, or even stripped. It retains full Rust panic strings and cargo dependency paths, including the build path C:\Users\user\.cargo\registry\src\index.crates.io-6f17d22bba15001f.
Additionally, the binary’s version flag reveals the project name as win_encryptor 1.0.
Figure 7: Ransomware’s CLI interface
⠀
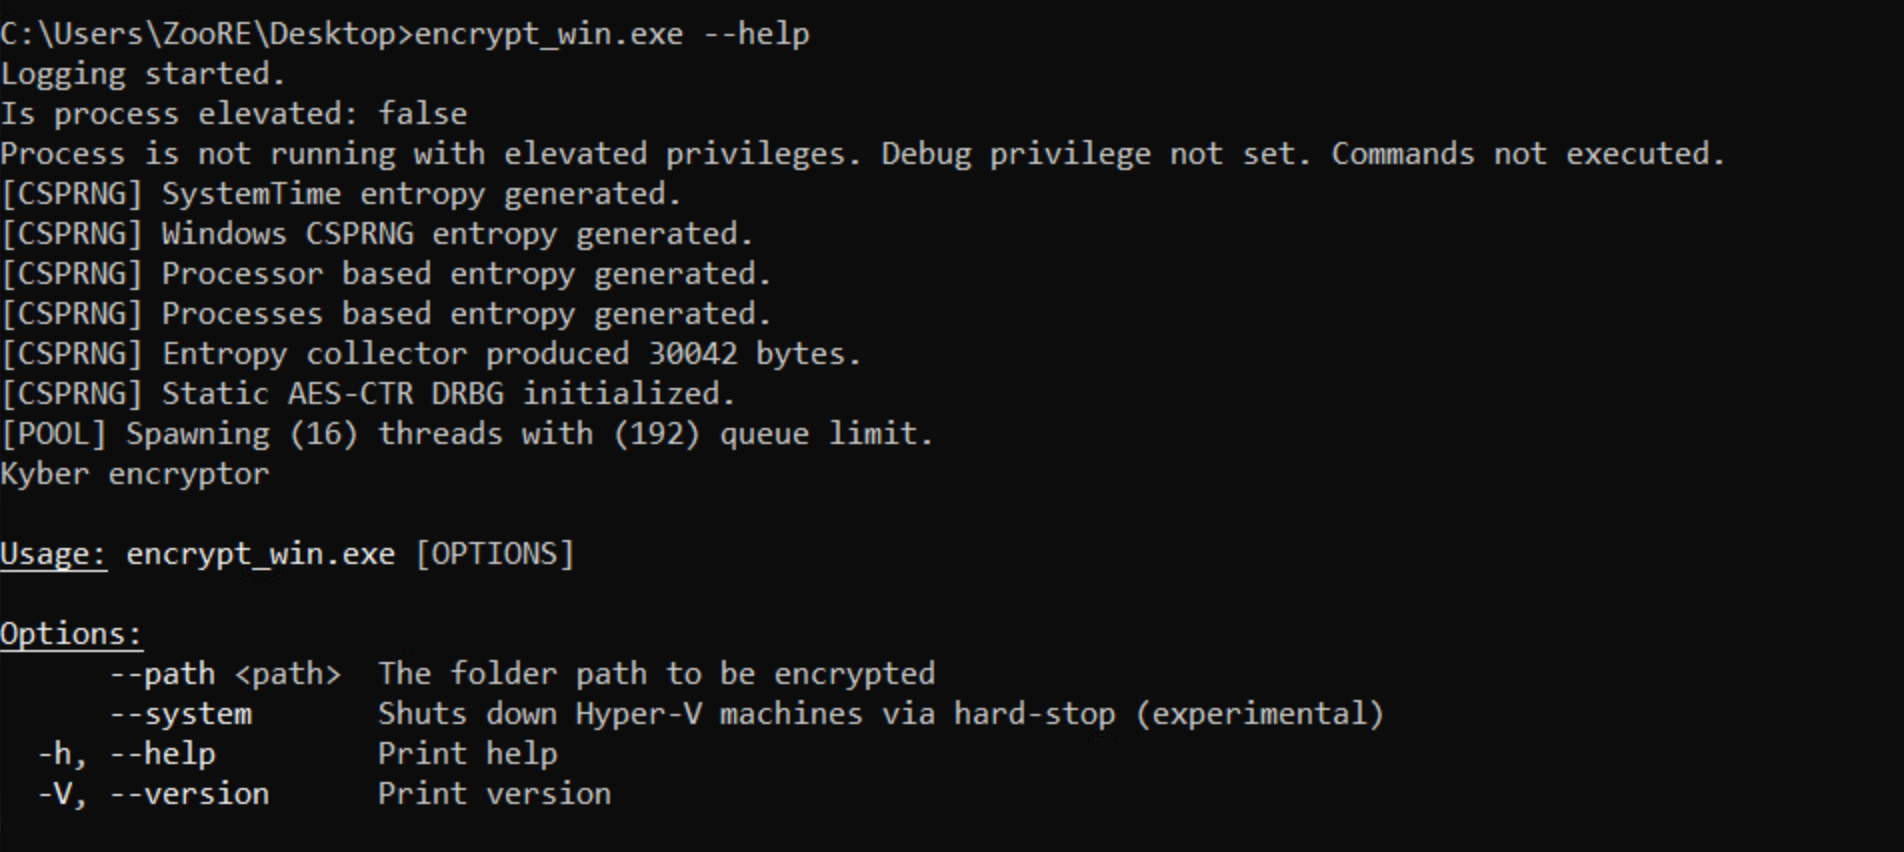
The Windows binary exposes a minimal CLI (Figure 8), requiring the path argument to specify the target directory. It also includes system flag which is self-described as “experimental” and intended to enforce a hard-stop on Hyper-V virtual machines.
Ransomware initializes full runtime initialization, even if invoked with just help flag. It aggregates entropy from four sources: system time, Windows CSPRNG, processor-based entropy via RDRAND, and running process data and producing ~30 KB of randomness to seed an internal AES-CTR DRBG. Unlike typical ransomware, which often relies only on BCryptGenRandom, this strain implements a custom entropy pipeline which suggests the developer cared about key material quality.
After initialization, the binary checks whether it is running with elevated privileges by attempting to acquire SeDebugPrivilege and logs are printed to the console (see Figure 8).
This privilege check determines if the destructive commands will be executed. Without elevation, the binary only does file encryption. With elevation, it unlocks its full toolkit: killing services, modifying the registry, and wiping shadow copies to prevent recovery.
Service termination and anti-recovery
When running with elevated privileges the binary first terminates services matching five patterns: msexchange, vss, backup, veeam, and sqlusing OpenSCManagerA, EnumServicesStatusA, and ControlServiceAPI calls. The malware forces the system locale to en-US before service enumeration. This normalization makes certain that pattern matching for service names remains reliable regardless of the victim’s native system language.
It then executes 11 commands via CreateProcessW that you can see in the table below
for /F “tokens=*” %i in (‘wevtutil el’) do wevtutil cl “%i”
Clear all Windows event logs
11
rd /s /q C:\$Recycle.Bin
Empty the Recycle Bin
Table 2: 11 commands executed by ransomware if it ran with elevated privilege
Hyper-V shutdown
If systemflag is set, the binary enumerates Hyper-V virtual machines via PowerShell before encryption:
Get-VM | select VMId, Name | ConvertTo-Json
Stop-VM -Force -TurnOff
Figure 8: PowerShell commands used for Hyper-V termination.
Each VM is terminated with a “hard stop” (-TurnOff) which forces an abrupt shutdown, releasing file locks so the malware can encrypt. As noted in the CLI help text, the developer currently considers this Hyper-V functionality “experimental.”
File encryption workflow
For each file, the binary checks for a prior encryption marker to avoid redundant processing. If the file is locked, the malware uses the Windows Restart Manager to identify and terminate the responsible process. If access is still denied, it modifies the file’s permissions (ACL) to Everyone:FullControl and clears the read-only attribute. It retries this entire sequence up to three times per file to ensure it can successfully open and encrypt the data.
Once encryption succeeds, the file is renamed with the .#~~~ extension, and a READ_ME_NOW.txt ransom note is dropped in the directory. Each successful operation is logged to the console as Successfully encrypted <file>. File size: <size>. To maintain system stability and to keep the OS bootable, the malware excludes critical system directories and files from encryption listed below:
$recycle.bin,perflog,system volume information,thumb,programdata,appdata,microsoft,netframework,c$, all users
Unlike the Linux variant, this sample actually uses what it claims: Kyber1024 and AES-256-CTR.
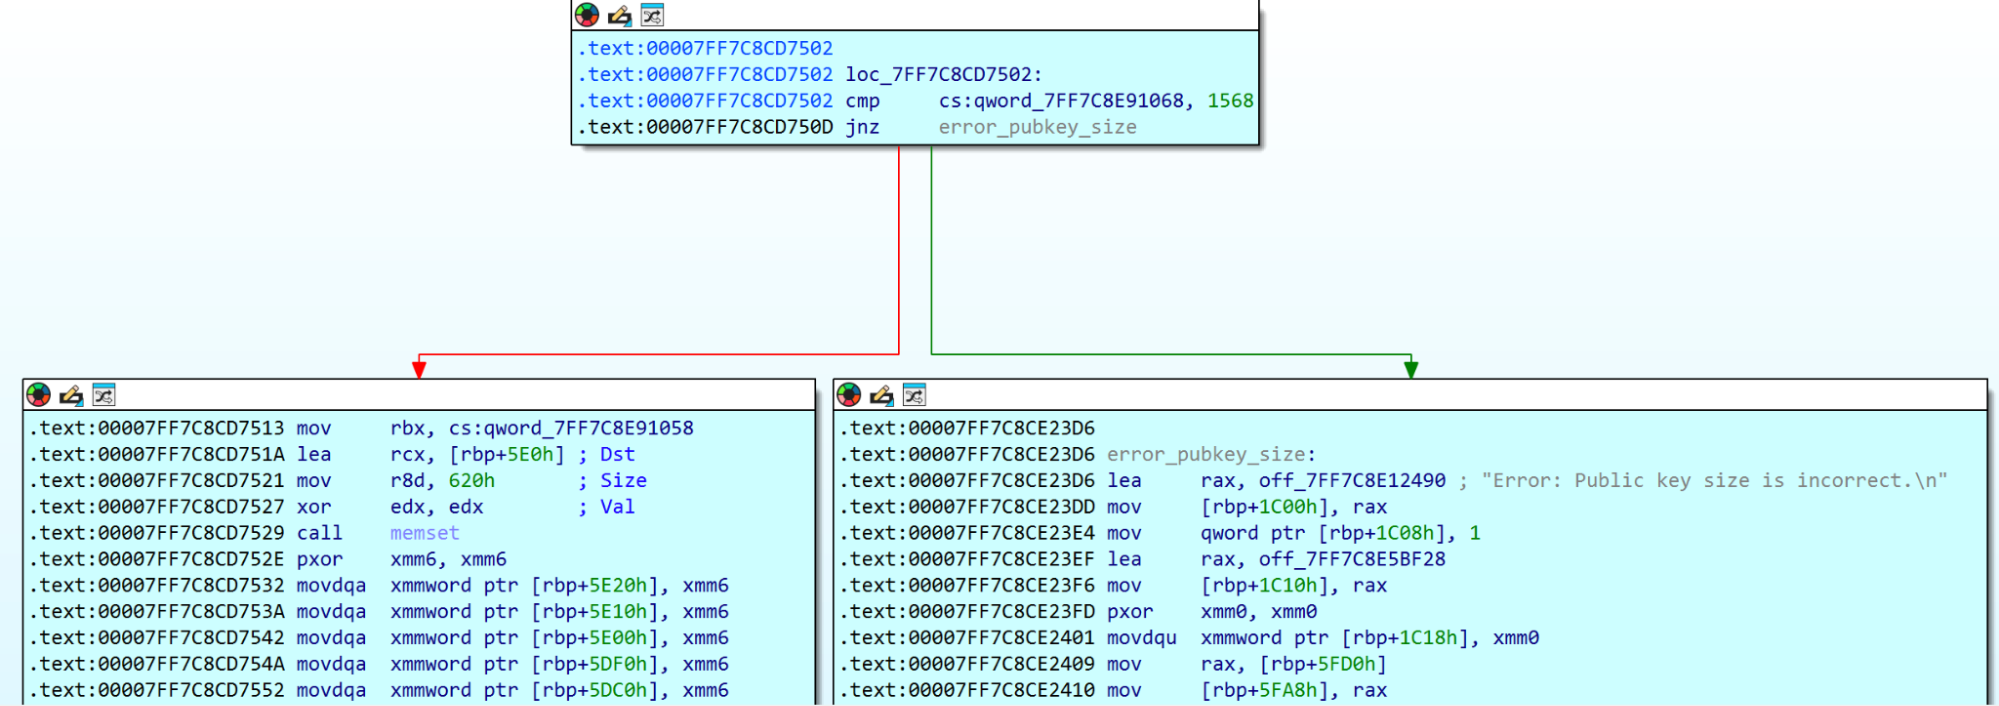
The sample uses a hybrid encryption design. The embedded public key is validated against the expected Kyber1024 public key size of 1568 (0x620) bytes.
Figure 11: Public key size check (1,568 bytes / 0x620) with branch to error on mismatch
⠀
Following validation, the sample initializes an AES-256 CTR context using a 32-byte key, which it expands into a 60-word key schedule.
This confirms that Kyber is not used for direct file encryption. Instead, Kyber1024 protects the symmetric key material, while AES-CTR handles bulk data encryption.
Registry artifacts and icon registration
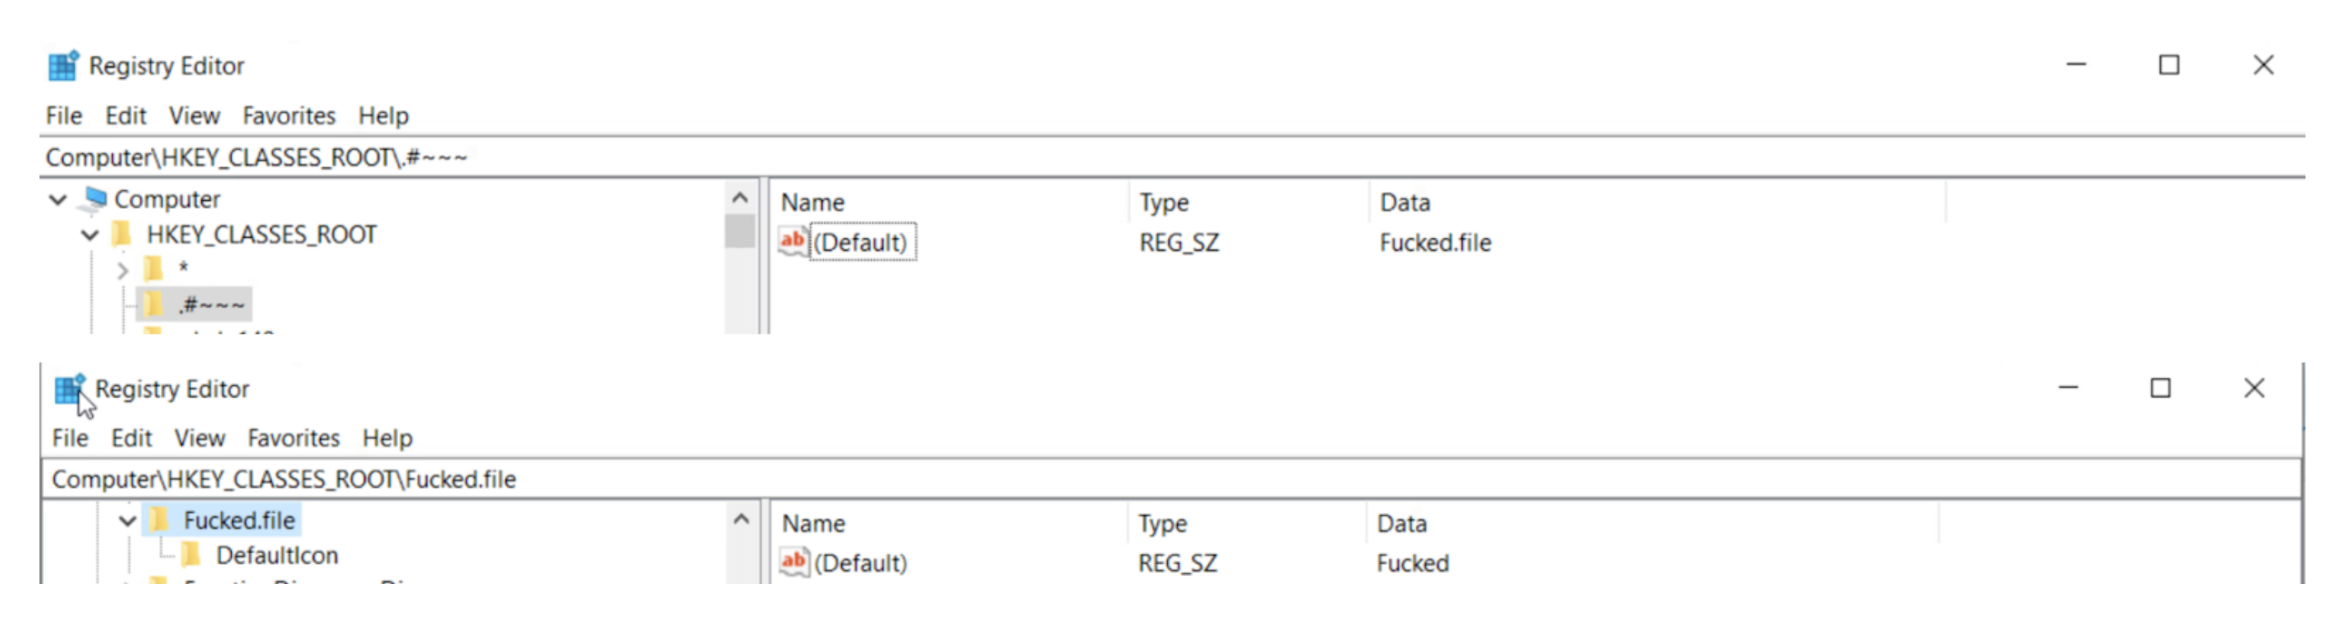
When executed with elevated privileges, the malware assigns a custom icon to encrypted files by registering the .#~~~ extension. It creates C:\fucked_icon\directory, writes processed_file.icon to that location, and configures it in the registry as the default icon.
Figure 12: Regedit output after execution of Kyber with elevated privileges
⠀
The malware executes ie4uinit.exe to refresh the shell icon cache. This forces Windows to display the new icons immediately across the filesystem without a system restart.
Mutex
The choice of the mutex is interesting. The mutex name boomplay[.]com/songs/182988982 is stored as a wide string in .rdata and appears to be a link to a song on Boomplay, which is a legitimate African music streaming platform. We were unable to identify the specific track due to geo-restrictions we could not bypass.
Mitigation guidance
Based on the observed Tactics, Techniques, and Procedures (TTPs), organizations should focus on the following defensive actions:
Harden virtualization infrastructure (T1021.004)
Kyber’s reliance on SSH for ESXi host access and native tooling like esxcli highlights critical control points.
Implement least-privilege access for ESXi shell and SSH, ideally disabling them entirely unless required for maintenance.
Enforce multi-factor authentication (MFA) on all management interfaces and accounts.
Monitor esxcli execution for VM termination (vm process kill) or configuration changes, which are late-stage indicators of compromise.
Kyber uses 11 distinct commands to impair defenses, including VSS deletion and log clearing.
Restrict execution: Prevent unprivileged users from executing command-line utilities like vssadmin.exe, wmic.exe, and wevtutil.exe.
Protect backups: Ensure backups (especially Veeam/SQL targets) are immutable and stored off-host or in segregated network segments that the Windows variant cannot reach, even with elevated privileges. The ransomware explicitly targets these services and file systems.
Detection focus (lateral movement & defacement):
Monitor for defacement artifacts: Actively monitor for changes to VMware’s management files (/etc/motd, /usr/lib/vmware/hostd/docroot/index.html, etc.) in ESXi environments.
Custom entropy check: The Windows variant’s custom entropy pipeline suggests an effort to ensure key quality. Analysts should incorporate the provided IOCs (mutex: boomplay[.]com/songs/182988982) and file extensions into their detection rules.
MITRE ATT&CK techniques
ID
Technique
Use
T1486
Data Encrypted for Impact
Primary objective for both variants.
T1485
Data Destruction
Deletion of shadow copies and backups via vssadmin and wmic.
T1489
Service Stop
Terminating ESXi processes and Windows database services.
T1070.001
Indicator Removal: Clear Windows Event Logs
Using wevtutil to clear logs after infection.
T1021.004
Remote Services: SSH
Primary vector for interacting with ESXi hosts.
T1562.001
Impair Defenses: Disable or Modify Tools
Disabling Windows Recovery Environment and boot failure prompts.
Kyber ransomware isn’t a masterpiece of complex code, but it is highly effective at causing destruction. It reflects a shift toward specialization over sophistication. The operators didn’t need custom exploits or zero-days, because they didn’t have to use them. Instead, they simply used the standard ransomware playbook of abusing native tools like esxcli and vssadmin, and it was enough.
The encryption claims in the ransom note aren’t the main story. If anything, they highlight a gap between the campaign’s marketing and its execution. The sophistication of the defense must now be measured against the attacker’s specialization, not their code complexity. Ignoring Kyber’s multi-platform nature is an acceptance of a total operational blackout.
AMD’s Ryzen 9000 series desktop processors are by now well into the second half of their lifecycle as AMD’s leading-edge desktop chips. With a complete product stack in play – ranging from 6 up to 16 CPU cores on a single chip – In most generations this would be where AMD would stand pat on […]
For us humans to interact with the online world, we need a gateway: keyboard, screen, browser, device. What is called “human detection” online are patterns that humans use when interacting with such devices. These patterns have changed in recent years: a startup CEO now uses their browser to summarize the news, a tech enthusiast automates the process to book their concert tickets when sales open at night, someone who’s visually impaired enables accessibility on their screen reader, and companies route their employee traffic through zero trust proxies.
At the same time, website owners are still looking to protect their data, manage their resources, control content distribution, and prevent abuse. These problems aren’t solved by knowing whether the client is a human or a bot: There are wanted bots and there are unwanted humans. These problems require knowing intent and behavior. The ability to detect automation remains critical. However, as the distinctions between actors become blurry, the systems we build now should accommodate a future where “bots vs. humans” is not the important data point.
What actually matters is not humanity in the abstract, but questions such as: is this attack traffic, is that crawler load proportional to the traffic it returns, do I expect this user to connect from this new country, are my ads being gamed?
What we discuss with the term “bots” is really two stories. The first is whether website owners should let known crawlers through when they are not getting traffic back. We have touched on this with bot authentication with http message signatures for crawlers that want to identify without being impersonated. The second is the emergence of new clients that do not embed the same behaviors as web browsers historically did, which matters for systems such as private rate limit.
In this post, we explore how web protection works today, and how it must evolve when the line between bot and human is fading.
The Web we had
When we use the Web, we don’t talk directly to the thousands of servers we interact with every day. We use Web browsers. These are also known as “user agents” because they act on our behalf, representing our interests so that we can safely shop, read, and watch the Web without giving sites access to our entire computer or phone.
Websites also have an interest in how browsers work. They want to make sure that their content is presented accurately (fits the screen on mobile, has the right background color, the correct language). Websites also want to ensure that people are able to complete a purchase, read their articles, use their microphone, or sign in securely without a password. They also want people to see the ads beside the articles.
This tension between the interests of browser users and websites has been going on for a long time. Publishers typically want pixel-level control over the experiences of their users, but the people on the other side of the browser often want to use the data they access in ways that weren’t envisioned by the publisher.
Web browser vendors and the standards ecosystem around them have paid careful attention to balancing these interests, sometimes with great controversy. For example, you can use browser extensions to block ads, but over time browsers have restricted what such extensions can do. Accessibility standards (e.g., WCAG) have paved the way for using Web content in ways that aren’t about pixels, backed in many places by regulatory requirements. One can question the specifics of each of those tradeoffs, but they come as a package: if you want to be on the Web, you have to accept it, whether you are a publisher or a user.
Now, however, that balance is shifting. Having an assistant summarize the news or aggregate research is not a new concept, but AI democratizes this capability for everyone. The friction comes from how these emerging clients operate. A human assistant might print an article or take a screenshot without the publisher knowing, but they still use a standard web browser to render the site in the first place. AI agents bypass this step, disrupting the balanced approach to publishers’ vs. users’ rights that browsers built. They quietly fetch the raw data without rendering the page. For publishers, because of their overlap with pre-existing browser traffic, these clients are inherently opaque. Website owners cannot tell if their fetched content is serving one private report (possibly distorted, possibly unattributed) or being ingested to train a model for a million users, which disrupts the predictable (and monetizable) traffic that keeps their sites online.
The implicit agreement that made the Web work is breaking down. To understand how, the next section goes over a common architecture on the Internet.
The client-server model
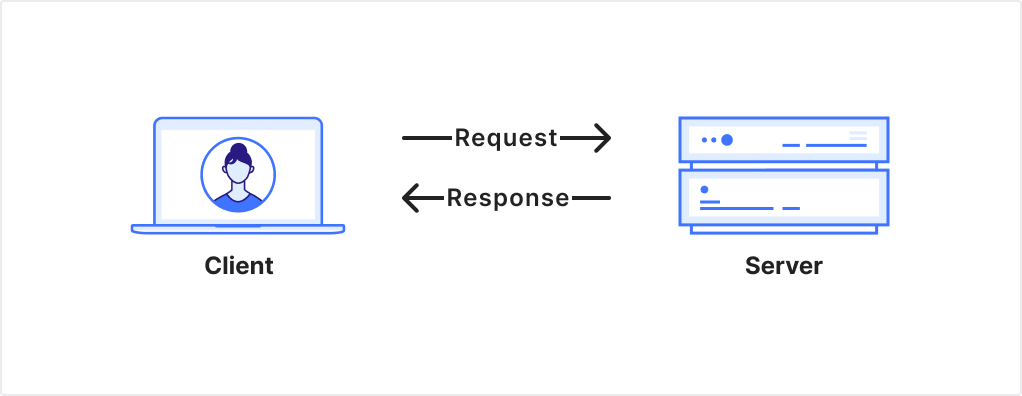
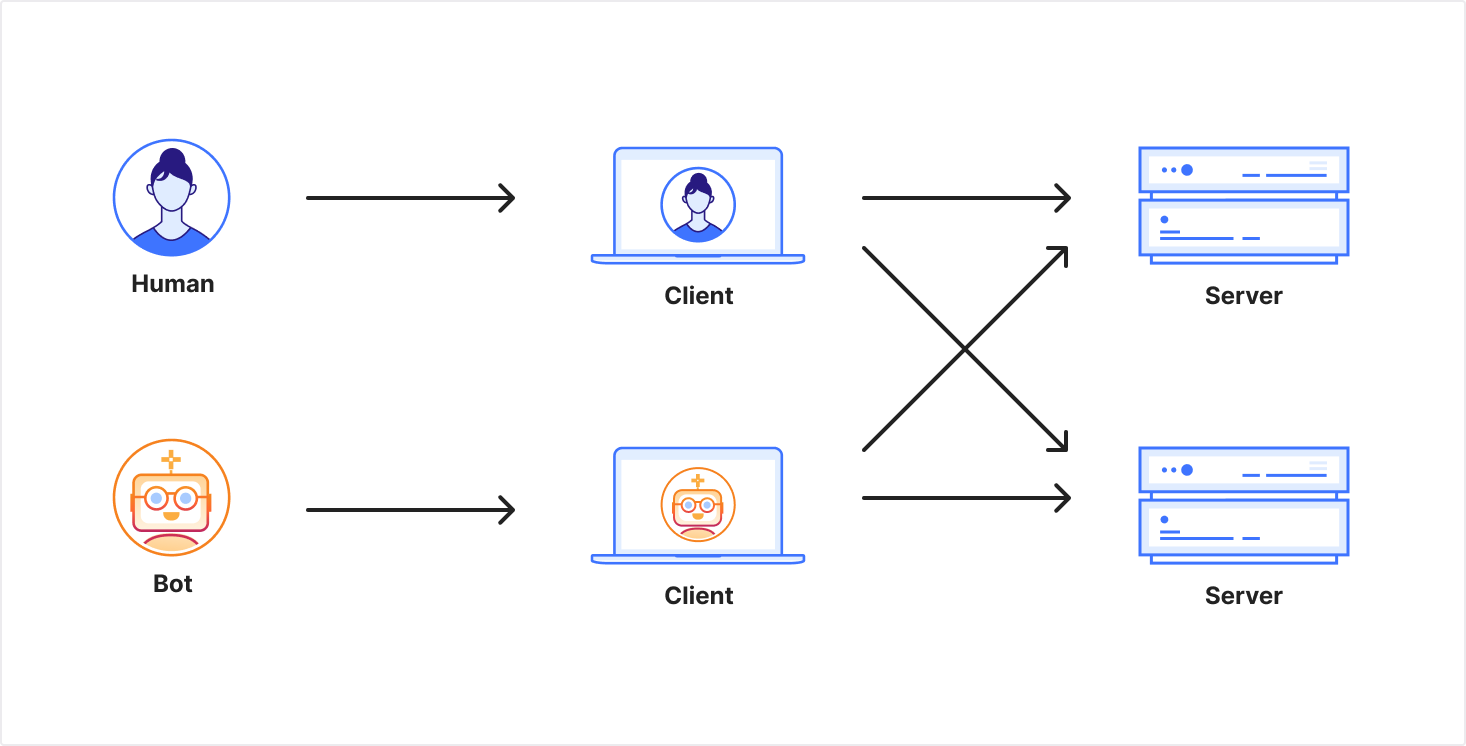
Let’s take a step back, and look at one of the main deployment patterns on the Internet: the client-server model. A client makes a request to a server to obtain a resource:
Figure 1: Client-Server model. A client sends a request which the server responds to.
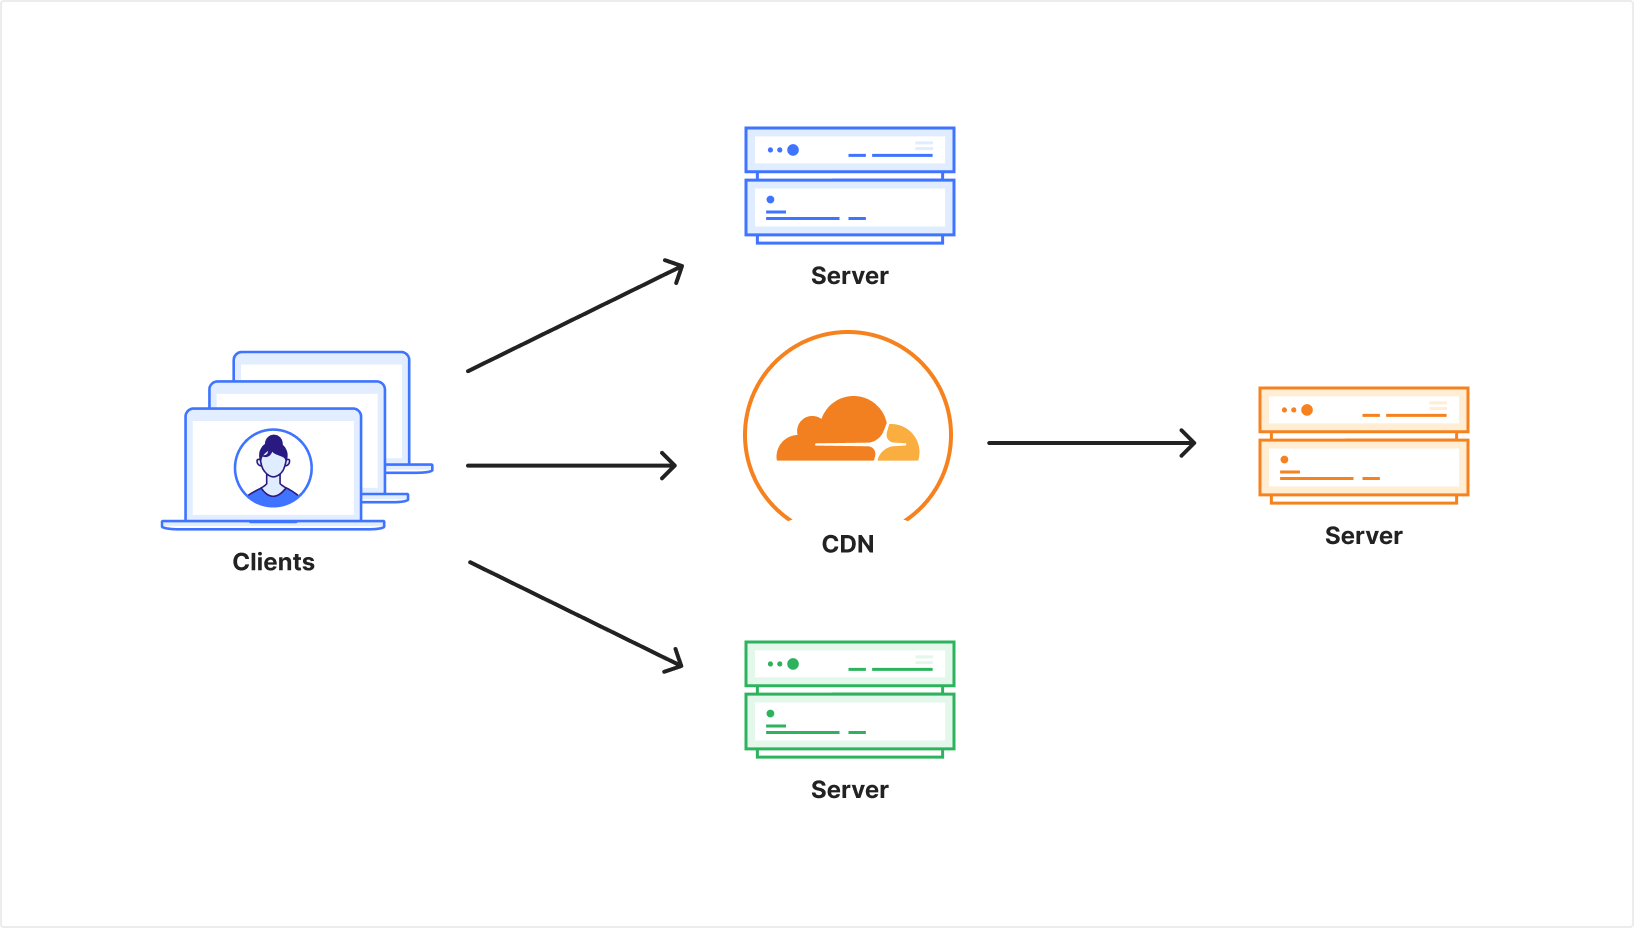
To handle more requests, a website can increase its capacity to serve; it can deploy additional servers or place a cache in front of static traffic. Similarly, the number of requests coming from the client side can increase if one client makes more requests, or if the number of clients multiplies.
Figure 2: Multiple clients send multiple requests to different servers, with one fronted by a CDN.
That simplicity is part of what made the Web successful. It allows many kinds of clients to exist, and it allows the network to evolve without each server needing to know exactly what software is on the other end.
Figure 3: Two different client contexts that send requests to servers. Each server only sees a request, but not the end-user behind it.
That openness also creates uncertainty. A website can see a valid request for a resource, yet it usually cannot know what happens after the response leaves the server: whether the content is rendered for one person using a keyboard, a mouse, and a screen to control a browser; or if it’s an independent program making requests automatically, archiving responses, indexing them, and feeding into a larger system.
Bot management today
This model works surprisingly well. That is why operating a website can be as simple as starting a web server with a connection to the Internet. It holds only until the server has to decide which requests it can afford to serve, trust, or prioritize.
Sometimes that is about capacity. If your service is provisioned to handle 100 requests per second globally, but you’re receiving 200, you have to drop certain requests. If your server only has 1 CPU but incoming requests require 2, you have to drop requests. If the cost of serving 200 is prohibitive, then you have to rate-limit all requests.
You can drop requests at random. It’s possibly unfair, and may miss the target by affecting wanted clients, but it works. In the absence of other signals, there is no other choice.
And capacity is only part of the picture. Servers also try to distinguish among clients for many other reasons: to separate attacks from ordinary traffic, to manage non-malicious load, to prevent extraction of data, to limit ad fraud, to prevent fake account creation, or to stop automated actions being taken on a user’s behalf.
The difficulty is that web clients are unauthenticated by default, while still exposing many partial signals. Therefore, most servers decide to apply access control logic based on the information they receive. If a single IP address is making 10x the number of requests as others, it might be blocked. A server that goes further might infer that this IP address is used by a VPN, and therefore proxies the traffic of more than one user. The service could decide to apply a coefficient: assuming each client can make 10 requests per second, a shared IP address would be allowed 100 rps before seeing their requests being dropped.
That’s one of the keys to bot management: it aims to provide the server with more information about the client to help it make decisions. This information is inherently imprecise, because the client is not under the control of the server. In addition, the same information creates fingerprint vectors that can be used by the server for different purposes such as personalized advertising. This transforms a mitigation vector to a tracking vector.
At a high level, the server sees the following signals from the client:
Passive client signals: required to make a request on the Internet. Clients necessarily send your IP address, and usually establish a TLS session.
Active client signals: voluntarily provided by the client, often invisible to the end user. This includes a User-Agent header or authentication credentials.
Server signals: information the server observes, such as the geographic location of the edge server handling the request, or the local time the request is received.
To limit and cap volumetric abuse, what matters to the origin is the capability and intent of the client to make multiple requests. In the case of an ad-funded website, the origin needs confidence that ads are actually displayed to the end-user. To preserve their brand, origins may want to ensure that the client has specific rendering capabilities: PDF reader, SVG renderer, virtual keyboard. And if the request is coming from an intercepting proxy, the origin may want to ensure that the request actually originates from an end client
If traffic grows then so do the costs to operate. If clients do not generate value, monetary or not, then the server has no incentive to cover those costs.
Different operators respond to this environment differently. Some large crawlers and platforms identify themselves because predictable access is worth the cost of being attributable. It may even help. Others try to avoid identification: because they expect to be blocked, because they seek anonymity, or because they are operating on behalf of end users. The result is an unstable balance built on partial signals.
This is why the human versus bots frame is misleading. What the origin cares about is not humanity in the abstract, but whether the client is behaving in ways the site can support.
There’s a fundamental tension in how we govern access on the Internet: decentralized, anonymous, accountable — pick two.
Fully decentralized + anonymous means no accountability. A blocked client can spawn a new account without impact on its reputation. This implies that origins have to invest more to manage their resources. This is the default of the Web.
Decentralized + accountable means everyone knows who you are, which works for certain use cases but has clear drawbacks. Think OAuth mechanisms such as “Log in with”, which requires account registration and revealing activity to a third party.
Anonymous + accountable likely requires governance, rules, and enforcement. No widely deployed system achieves both properties for the same actor. The closest precedent is the Web PKI, where governance (CA policies, Certificate Transparency) holds servers accountable. When that governance fails, there are consequences. No equivalent exists today for the client side.
Current tools build on elements from that first space to strive for the second: TLS fingerprints, IP addresses, robots.txt. They attempt accountability, but only hold as long as the derived fingerprints remain stable.
The important distinctions are what, not who
For a website owner deciding how to handle incoming traffic, the meaningful distinction isn’t necessarily bots vs. humans. It’s about balancing the origin’s needs to understand the traffic it receives with the clients’ needs to preserve their privacy.
Platforms and services that want to be identifiable
Figure 5: A crawler makes multiple request to a server
Some traffic comes from known operators making high volumes of requests: search engine crawlers, cloud platforms, enterprise infrastructure. These actors often have low privacy expectations. They’re infrastructure making millions of requests from identifiable sources. The ability to identify the source of a request helps to mitigate misjudgment if an infrastructure provider is sending you too many requests or accessing pages it should not. Self-identification is one of the principles for responsible AI bots we proposed. It is based on these principles that Cloudflare operates its URL scanner for Radar, or how we expose crawling capabilities.
For this traffic, identity works. More precisely, some operators can tolerate attributable requests because reliable access is worth it. Web Bot Auth using HTTP Message Signatures allow operators to cryptographically sign their requests. OpenAI, Google, Cloudflare, or AWS, for example, sign requests originating from their platforms. Origins can verify “this request really came from the platform infrastructure” without relying on IP ranges or User-Agent strings.
Humans and other end-users rightfully have expectations other than being identifiable, to preserve anonymity without sacrificing their access and quality of experience.
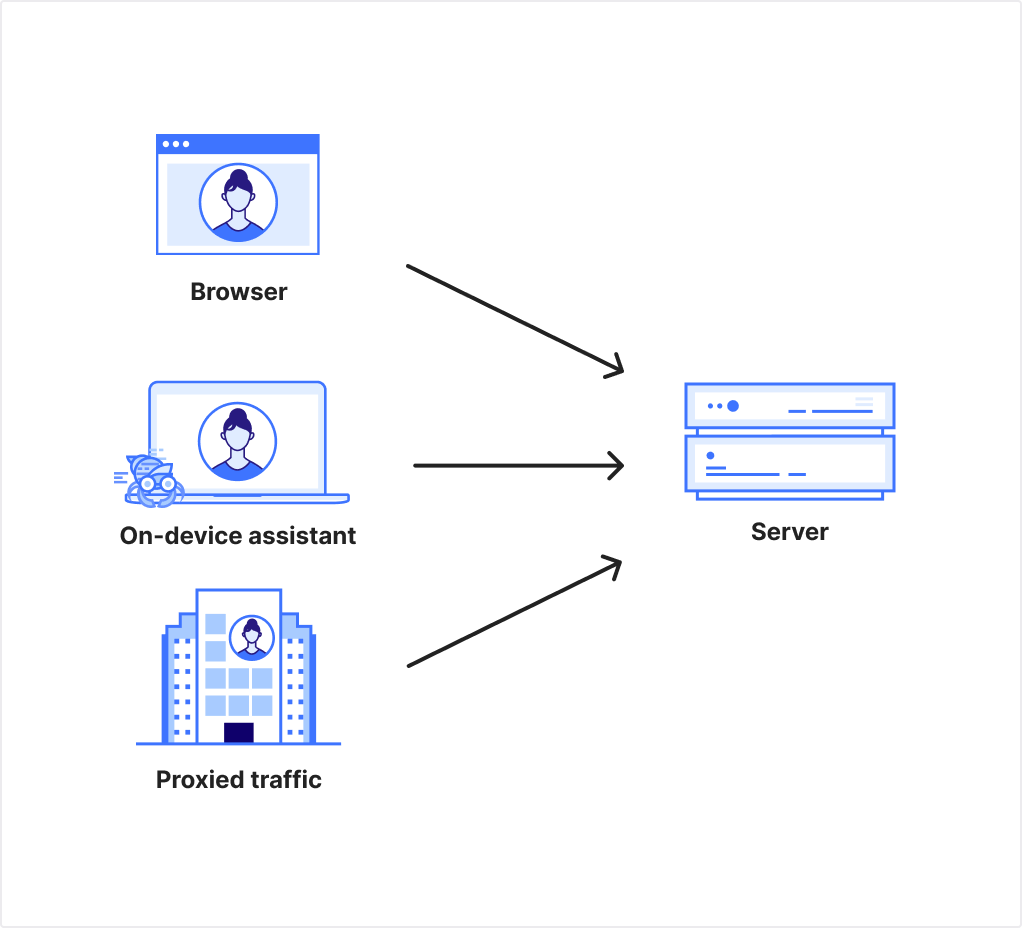
Distributed traffic that needs anonymity
Figure 6: Three distinct browsers make a request to a server. One is operated by a human, one by an on-device assistant, and one is proxied through a corporate proxy.
Other traffic comes from many sources, each making relatively few requests. This includes humans browsing the web, researchers doing measurements, scrapers using residential proxies, and increasingly, AI assistants acting on humans’ behalf.
And increasingly the distinction between bots and humans is moot. There is no meaningful difference between the AI assistant booking concert tickets and the human who would have done so manually. Both are distributed. Both need anonymity. In each case, an origin would want to create less friction for users who wish to use the service as intended, rather than abuse it.
Identity could work. To replace the old assumption we had for IP addresses, it should provide a unique, verifiable set of attributes tied to a specific client, proven through an account login, an email address, or a hardware key. However, it implies the need to present this identity when accessing websites. It also undermines privacy.
We want to build modern solutions that prove behavior without proving identity.
Anonymous credentials for the Web
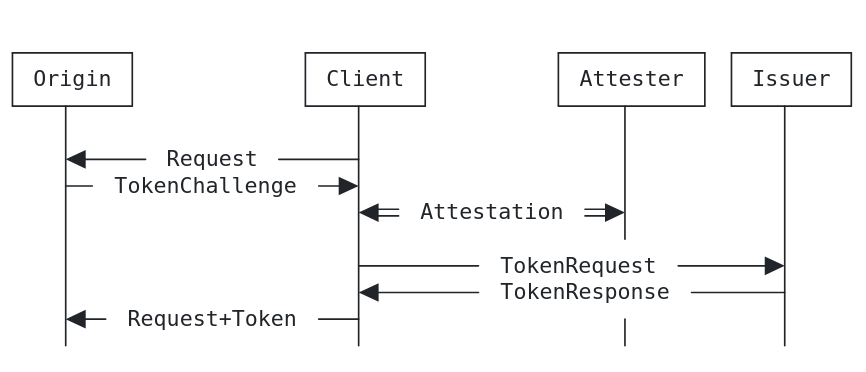
Since 2019, clients accessing websites via Cloudflare have been able to provide such proof of behavior, by sending a privacy token along with their request. This is due to Cloudflare’s early support for Privacy Pass. Privacy Pass, as standardised in RFC 9576, RFC 9578, lets a client carry an issuer-backed proof of some prior check, such as having solved a challenge, without turning that result into a stable identifier. It defines tokens that are unlinkable with any prior visit, request, or session.
This matters because it offers a different model from fingerprinting. Instead of collecting passive signals, the server can ask the client for an active privacy-preserving signal.
Figure 7: Privacy Pass Redemption and Issuance Protocol Interaction from Section 3.1 of RFC 9576
The RFC highlights four roles. The issuer trusts one or more attesters to perform some checks before issuing credentials (tokens in the RFC case). The client holds these credentials and decides when to present them, within the right scope. The origin remains in control of which issuers it trusts and what each presentation means. This does not remove abuse or policy questions, it simply provides clients and servers with a privacy-preserving way to handle them.
The system is simple, but it also has bounds: it does not, for example, allow for dynamic rate limits. If a client is issued 100 tokens, and starts consuming too many resources after the first or second session, there’s no way to invalidate the remaining tokens that were previously issued.
In addition, because of the unlinkability property, it’s hard for new issuers to emerge. There is no feedback mechanism that an origin can provide regarding the quality of the signal an issuer token conveys.
Finally, there’s a 1:1 relationship between the number of tokens that an issuer provides, and the number of unlinkable presentations that can be made with those tokens when they are redeemed: one token per presentation. Ideally, we would like a system in which the client contacts an issuer once and can later make multiple presentations scoped to a particular origin context. That points toward user agents holding vouched credentials and presenting proofs derived from them, rather than repeatedly acquiring single-use tokens.
With ACT, for instance, clients can prove something like “I have a good history with this service” without revealing “I am this user.” ACT preserves unlinkability between presentations at the protocol level, which is the key cryptographic property here. Even in the joint issuer-origin deployment model in Section 4.3 of RFC 9576, the protocol is designed so that token issuance and presentation are not directly linkable. That does not eliminate correlation through other layers such as IP addresses, cookies, account state, or timing. The same properties can be provided using standardized VOPRF and BlindRSA primitives within the reverse flow framework that ACT implements.
A successful ecosystem needs to be an open issuer ecosystem. In practice, that means more than saying anyone can mint credentials. Origins need to be able to decide which issuers to trust. User agents need a consistent way to present what is being requested. The ecosystem also needs ways for issuers to establish reputation and for relying parties to stop trusting low-quality issuers. No single gatekeeper should control participation.
To make this work, there needs to be a protocol and client API that works across browsers and other user agents. It has to be simple to deploy, clear to users, and narrow enough that browsers can place limits on abusive proof requests rather than merely surfacing them.
The trajectory if we do nothing
Website owners are already reacting to the disruption caused by emerging clients. This is partly caused by large-scale scraping and model training, and also by user agents acting in ways sites did not anticipate. Websites, therefore, have asked for more technical means to block AI crawlers and associated tools. In an ecosystem where the lines between bots and humans are increasingly blurred, the measures we have today will become less effective on their own.
If those measures aren’t effective, we can expect sites to pivot: requiring an account to see any content, or tying access to a stable identifier. This means no more ad-supported login-free articles, no more “three free articles a month.” Other content businesses may move away from the Web completely, offering their data and services directly to AI vendors for a fee, or within walled gardens operated by large platforms.
These outcomes are bad. Everyone benefits from the open access to information that the Web offers. It is not that all sites will make these choices. There are many reasons for offering content online, and not all of them are commercial. But if enough sites do, they change what “normal” is on the Web to be something worse.
That matters because the open Web is an environment in which different clients can gather information from different sources without relying on a handful of players. We also benefit from having a diversity of sources of information. On a Web where access to information is largely mediated through a small handful of companies, we put too much power into too few hands. The result is not just more friction for anonymous clients, but a more brittle Internet with fewer ways for publishers to meet users.
Anonymous authentication brings some risk, too
We should be clear about what we’re building. Infrastructure for proving properties can become infrastructure for requiring properties. Anonymous credentials are meant to prove something about their holder; for example, “I solved a challenge” or “I have not exceeded a rate limit.” But a system that can prove any single attribute is also capable of proving other attributes, which is a source of concern.
Today, presenting a Privacy Pass token may convey “solved a CAPTCHA”. Tomorrow, the same systems could prove entirely different attributes. For instance, issuing tokens only to devices that “have device attestation” excludes older devices and their users. Similarly, requiring attributes such as “has an Apple or Google account” excludes users of non-mainstream platforms.
Once the infrastructure exists to verify anonymous proofs, what gets proven can expand. We need to make sure this does not gate access to the Internet.
Why we should build it anyway
Gates already exist. Platforms increasingly require identity. Websites are blocking traffic coming from shared proxies. The question isn’t whether gates will appear, it’s whether the user remains in control of their privacy.
As we’ve discussed, bot management requires some signals to be shared. The alternatives to anonymous proofs are worse. Without the ability to prove attributes anonymously, every gate requires fingerprints: retry from a specific browser, link your account, don’t use a VPN. These may not even be options to people, such as the ones which have no idea their connections are proxied.
Privacy-preserving credentials do not remove the need for trust or policy. They can make those demands more explicit and less pervasive. Unlike fingerprints, proofs are explicit. Users can see what is being asked, and clients such as web browsers and AI assistants can help enforce consent.
To decide, use this guardrail
There is a simple test to evaluate the next methods for the Internet that serves everyone: do the methods allow anyone, from anywhere in the world, to build their own device, their own browser, use any operating system, and get access to the Web. If that property cannot hold, if device attestation from specific manufacturers becomes the only viable signal, we should stop.
This means we need to foster an open issuer ecosystem, where no single gatekeeper decides who can participate. In the rate limit trilemma, decentralization is mandatory on the open Web. We don’t yet know fully how to build it, but we know we need to foster it.
A new balance
Until now the Web has largely been in balance. Some aspects may have been a happy accident, while others could have been inevitable. For many end users and publishers, it worked because the Web stayed open enough to support a variety of clients accessing a similar variety of resources.
That balance is at risk. Privacy-preserving primitives for the Web are one attempt to build a different outcome: privacy-preserving, open, accountable. It is not guaranteed to succeed. But it is better than waiting.
If you are interested in tracking and participating, this work happens in the open at the IETF and at the W3C. We believe the existing places where people gathered to shape the Web of today are the best places to design the Web of tomorrow.
A new open-source bridge helps customers connect Rapid7 vulnerability data to AI agents, assistants and custom workflows with more flexibility, control, and faster access to insight.
Security teams want more from their data than APIs and one-off reports.
They want to ask better questions, move faster, and bring security context into the workflows they are already building. That’s especially true as more organizations experiment with private AI assistants, internal copilots, and LLM-powered automation. Part of this experimentation is, of course, attempting to lower the pressure on teams that have to figure out how to prioritize the sheer number of actionable vulnerabilities efforts like Project Glasswing are quickly becoming hyper-skilled at spotting.
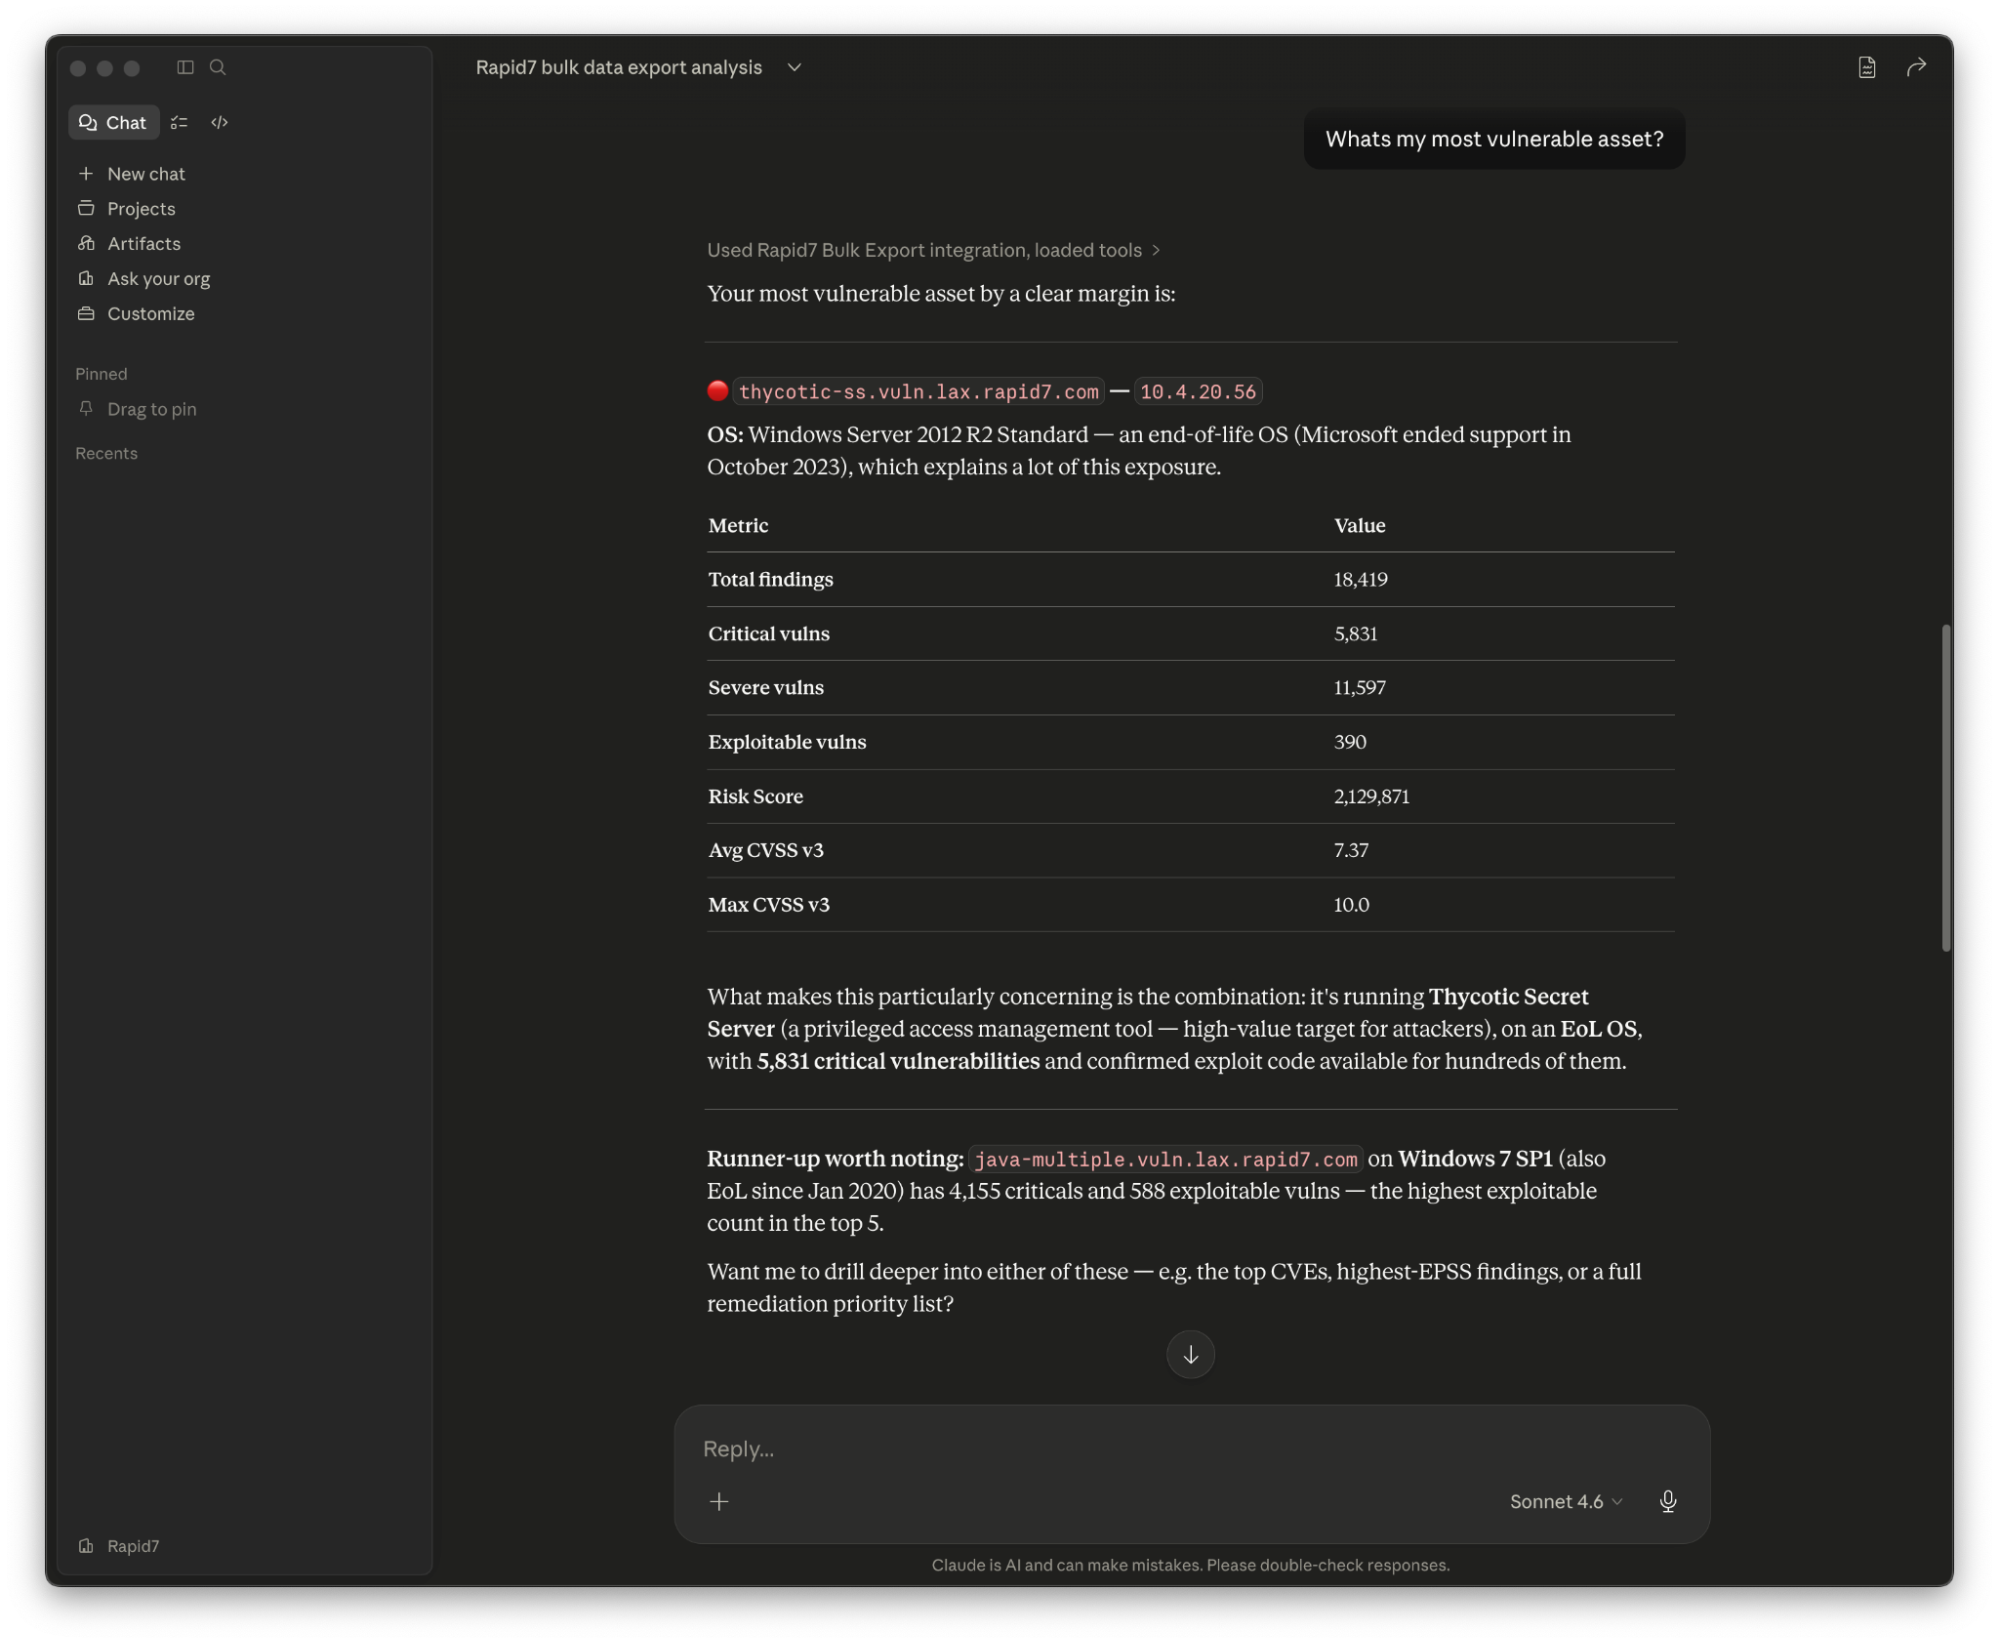
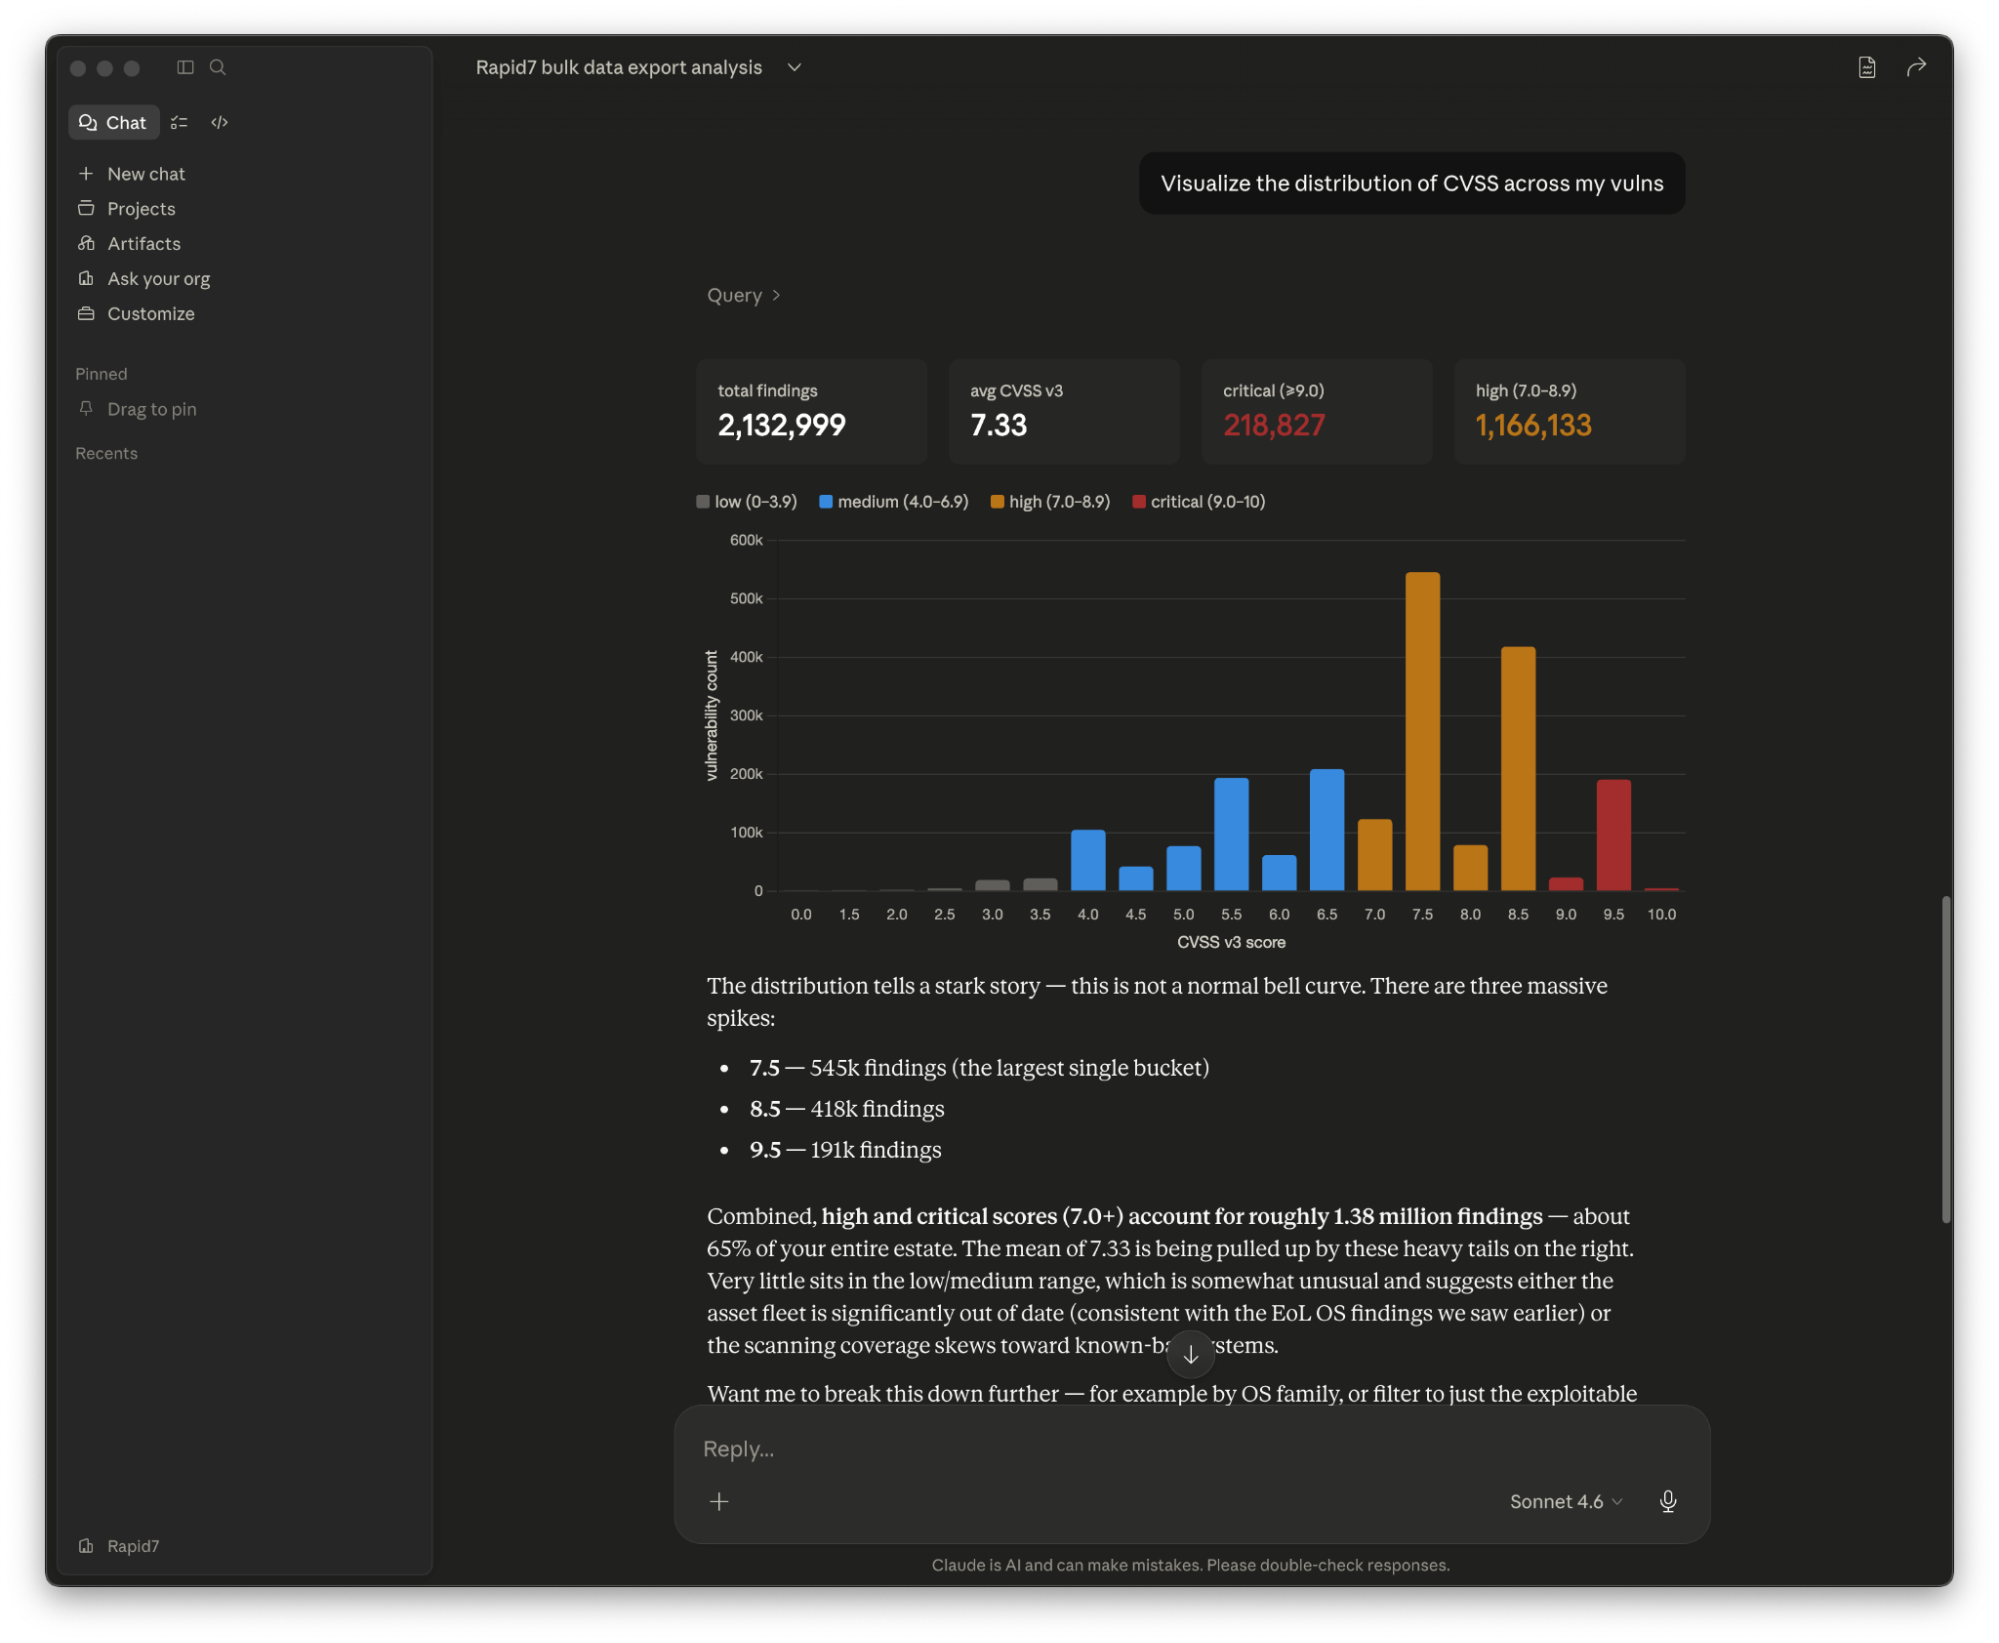
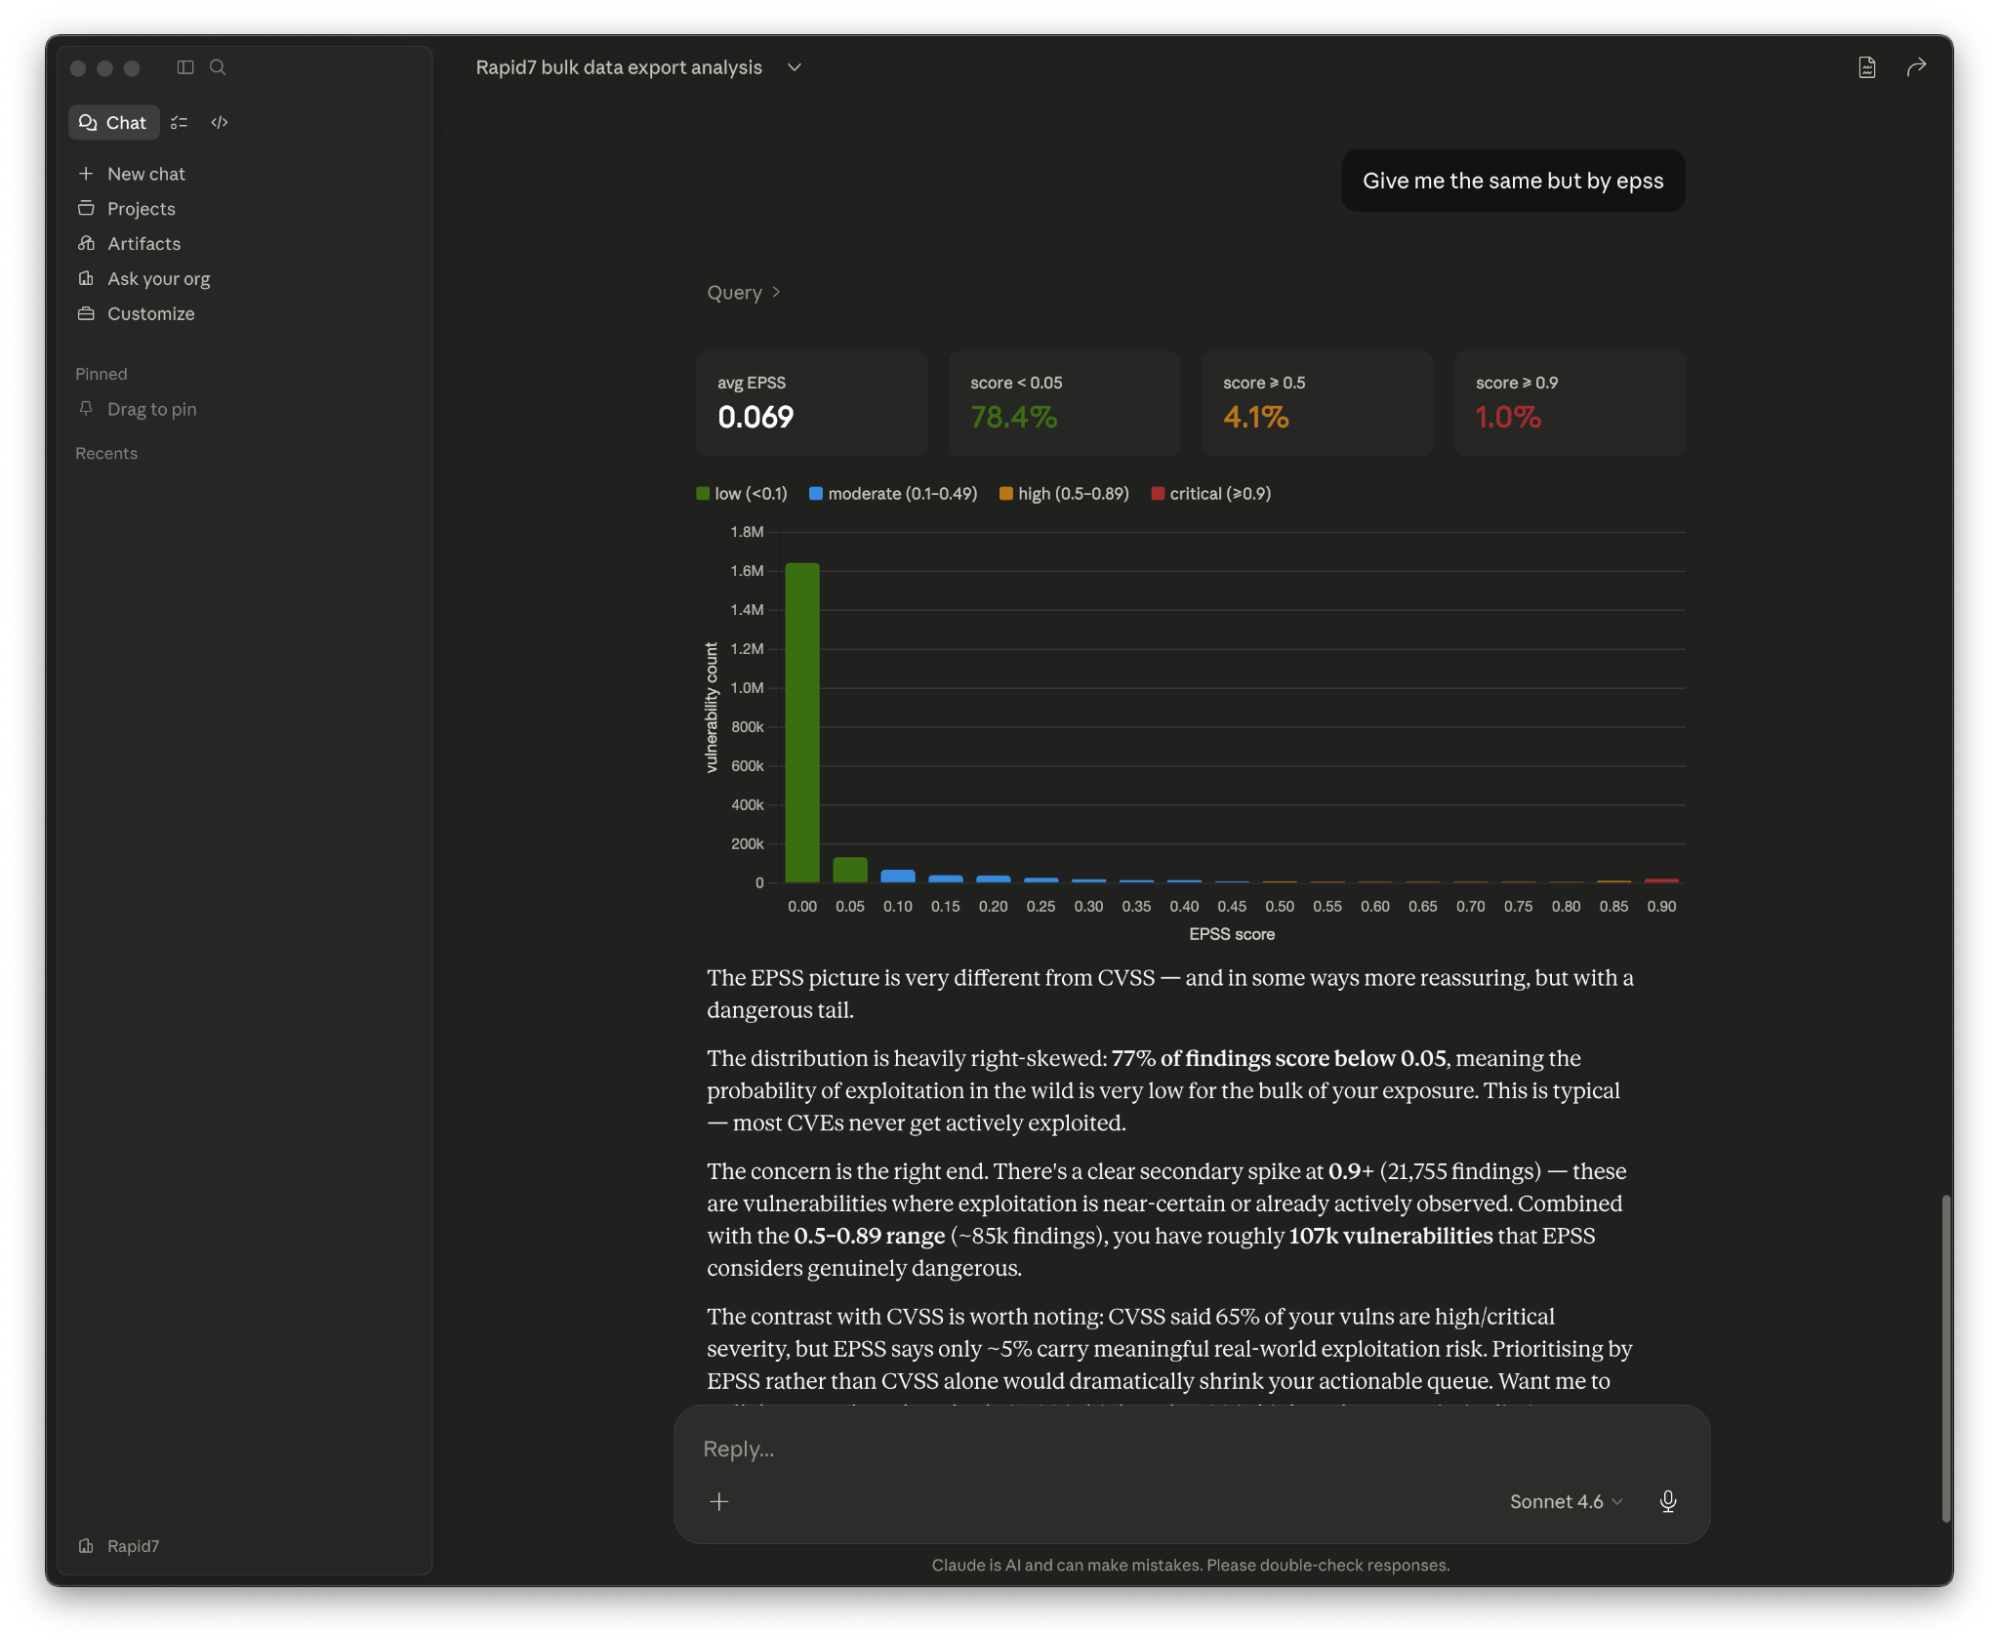
That’s why Rapid7 is introducing a free, open-source MCP Server and Agent Skill for Bulk Export. Bulk export is a highly efficient way to access all your Rapid7 data; no more paging APIs, no more verbose output. Bulk Export creates a local offline replica of your data the LLM can efficiently and quickly interrogate, reducing token cost and time to answer questions.
This new MCP and Agent Skill gives customers a standardized way to connect Rapid7 vulnerability and exposure data to AI assistants and custom AI workflows. Built as an open-source bridge, it helps customers bring their Rapid7 data into the tools and experiences that work best for their teams.
Why this matters now
Security teams are no longer just buying tools. They’re connecting systems, shaping workflows, and testing how AI can help analysts, IT teams, and leaders get to answers faster. For many teams, the path from raw security data to usable AI context is still manual. It often means exporting data, building wrappers, shaping queries, and managing custom integrations.
Rather than leave every team to solve that challenge from scratch, we wanted to provide a stronger foundation that is flexible, practical, and easy to extend over time. With projects like Metasploit and Velociraptor, Rapid7 is committed to Open Source, and by sharing with the broader community we hope to accelerate velocity and ensure we’re able to incorporate more use cases and fixes. These processes also give customers full visibility of the code running and tools used, ensuring data privacy and allowing the user to do with their data what they please.
What MCP does
Model Context Protocol, or MCP, is an emerging standard for helping AI systems interact with external data and tools in a structured way.
In practical terms, it gives AI assistants a cleaner way to ask questions, retrieve data, and work with systems beyond the model itself. For customers, that means less custom glue code and a more consistent way to use security telemetry in AI-driven workflows.
That matters because many security reporting and analysis workflows still assume a high technical bar. Answering a simple question can require custom queries, SQL knowledge, or dashboard work. But the people who need those answers aren’t always security specialists. They may be IT partners, compliance stakeholders, or executives who want clarity but might not need to understand the underlying query logic.
The MCP server helps lower that barrier: Instead of starting with raw exports and working backward, teams can start with the question they need answered.
CTEM is about helping teams move beyond point-in-time findings toward a more continuous, contextual understanding of risk. That requires security data that can be accessed, connected, and used across the workflows teams rely on.
Bulk Export helps make that possible by giving customers more flexibility in how they use Rapid7 data. The open-source MCP server makes it easier to bring that data into AI-assisted and custom workflows.
⠀
That can support more continuous exposure management workflows by making it easier for teams to triage vulnerability and exposure data. For example, an analyst facing a large queue of new vulnerabilities could use LLM assistance to quickly narrow in on the findings most likely to need attention first. Instead of manually working through exports and queries, they could ask natural-language questions to surface the exposures tied to critical assets, unresolved remediation work, or other signals available in the data.
From data portability to AI-ready interoperability
Bulk Export was already an important step toward giving customers more control over their data. It made it easier to extract and use security telemetry in external tools and analytics environments.
The open-source MCP server builds on that foundation: Instead of using exported data only for dashboards or custom reporting, customers can now use that same data in AI-native experiences. That includes internal assistants, private copilots, workflow automation, and natural-language exploration of vulnerability and exposure data. This makes existing security data easier to use in the environments customers are already investing in.
How it works
At a high level, the architecture is straightforward. Using the Agent Skill, your LLM runs the MCP server locally and automatically prepares the environment by performing the bulk export and loading the data into a local file store. The Agent Skill provides the schemas and knowledge, with the MCP providing the tools to access this data. The LLM then will answer any question by querying, summarizing, and synthesising data locally – an extremely fast and simple process that’s for the LLM.
Depending on the data a customer exports, answers can include vulnerability records, asset data, remediated vulnerabilities, and policy-related results.
The point here isn’t just that a model can access the data, it’s that an open-source layer helps customers inspect, adapt, and extend over time, empowering teams to control how that connection works in their own environment.
What customers can do with it
This opens the door to practical use cases, including:
Using LLM assistance to triage vulnerability data faster
Asking natural-language questions to spot exposure and remediation trends
Investigating which assets are tied to the most urgent vulnerabilities
Understanding what changed over time without manual analysis
Exploring policy failures without building manual queries
Feeding Rapid7 telemetry into private AI assistants and internal workflows
Making reporting more accessible for non-technical stakeholders
⠀
For teams already trying to operationalize AI, this creates a lower-friction path. Instead of building every integration from the ground up, they can start with a reusable bridge and focus on the workflows they want to enable.
A better path from data to action
Security data only creates value when teams can use it. For many organizations, turning raw telemetry into timely answers is still harder than it should be. Analysts need speed. Leaders need clarity. Builders need flexibility. And more customers want security data that works inside the tools and workflows they already rely on.
The open-source MCP server for Bulk Export is designed to help make that possible.
Bulk Export helps customers take control of their data. This is the next step: helping them put that data to work in AI-ready security workflows.
Добре е да знаем върху какво реално се гради отвъдната кулинария. И тук Сунната се притичва на помощ, поне отчасти. Разказите за живота на Пророка (хадиси) и кораничните коментари (тафсири) са в основата и на по-късни съчинения, свързани с храната и питиетата в отвъдното. Ето, дошли съратници при Пророка и го питали дали в Рая хората ядат и пият, и той отвърнал с категоричното „Е, как да не!“. Не само ядат и пият, ами и всеки от тях ще има силата на сто мъже в ядене, пиене, сексуално желание и сношение. Ето я връзката с разказа за хуриите, па и напомня за нашенското „ядене, пиене, тия три неща“, тоест четири.
А че не си говорим за веганско или вегетарианско преживяване, ни свидетелства сам Пророкът, според когото
първото ястие, с което са посрещани обитателите на Рая, е опашатият лоб от черния дроб (зийадат ал-кабд) на кита,
или принципно, голяма риба (хут, нун). Но не ни казва как ще бъде приготвен – суров ли, печен ли, грилован ли, маринован ли, как ще бъде „плейтнат“, да употребим модерен кулинарен термин. Според някои предания, използвани в отговор на фетва от началото на това столетие на авторитетния катарски портал за фетви, „царят на храните“ в Рая е месото, а на питиетата – водата.
Сунната ни отговаря и на въпроса за ходенето по голяма и малка нужда. Обитателите на Рая ще ядат, ще пият, казва Пророкът, но няма да плюят, няма да изпускат ни изпражнения, ни урина, ни сопол. Вместо това
храната ще излиза от телата им под формата на оригване и пот с аромат на мускус.
И ако историята си има начало със Сътворението, разгръщане с отделни акценти под формата на пророчески разкази, завършващи с живота на самия Мухаммад, сетне и управлението на мюсюлманските владетели, логично е и да завърши с разказ за бъдещето и отвъдното. Това прави и Ибн Касир, големият богослов и историк от XIV век, в показателно озаглавеното си съчинение „Начало и край“, известно като „Историята на Ибн Касир“. Последната част от него е посветена на въпросите на Ада и Рая. Не сме свикнали да виждаме в историческа енциклопедия неслучили се още събития, но не забравяйте, че историческият процес върви по предначертани релси. И вече е описано какво предстои: в катарското издание от 2015 г., с което разполагам, „краят“ е описан в том 17 с обем около 500 страници, Аллах да му се смили!
Винаги е впечатляващо човек да се сблъска със съдържанието на подобни обемисти текстове, които представляват нещо като „безкрайността на списъците“ (по Умберто Еко). Разгледани са знаците за настъпващия край на времето („Знаците на Часа“), Лъжемесията – мюсюлманският Антихрист (Ад-Даджжал), начинът, по който този свят си отива и настъпва отвъдното, сбирането на хора на тълпи за Съдния ден, как Аллах точно идва, мостът (сират) над адския огън, описания на адските мъчения, реките в Градината, хуриите, че даже и райският пазар, който става всеки петък и където хората, вместо да купуват и продават, се социализират. Ибн Касир няма как да пропусне и храната на обитаващите Рая и Ада. В Ада грешниците, както казва и самият Коран,
ще горят в пламтящ огън, ще им се даде от кипящ извор да пият, не ще имат друга храна, освен тръни, които нито угояват, нито избавят от глад (88:4–7).
И тези тръни, когато биват изяждани, засядат между устата и стомаха (нали и така казва сам Аллах, „храна, която присяда“ (73:13), та затова и не насищат, а носят само мъчение. А гнойната вода, от която грешникът „отпива и едва я преглъща, и смъртта го настига от всички страни, ала не е мъртъв и му предстои жестоко мъчение“ (14:17), е описана като питие, което изпича кожата на главата и я свлича, след което разкъсва вътрешностите, когато бива погълната, и излиза от тялото от естествения му изход. А ако дори капка от дървото Закум падне в моретата на целия свят, ще ги вгорчи и направи негодни за живот. Доколкото страховитото дърво в дъното на Ада е основен топос в Корана, всеки значителен кораничен коментатор му отделя внимание. Големият коментатор Ат-Табари от X век например, когато говори за главите на сатаните като плод на адския „олеандър“, който е и храната на всеки грешник като разтопен метал в стомасите, пояснява, че той е „като олово, злато или сребро“, прогарящо вътрешностите. Това било най-близката аналогия в този свят.
Да загърбим обаче старите арабски хоръри и да видим какво е положението с храната в Рая при Ибн Касир. Реките там са описани с големината на морета. Море от мляко, море от вода, море от мед и море от вино. Коритата им са покрити с бисери и чист мускус. Силата на сто мъже в ядене, пиене и съвкупление е също устойчив разказ за Рая. Също и този за липсата на телесни нужди, при което храната се изпарява през кожата под формата на пот с аромат на мускус. А виното на оня свят няма нищо общо с нечистите вина на този, разбира се. Реката с вино, подобно на другите реки там, извира изпод хълмове от мускус и не е омърсена от тъпкането на човешките нозе, които изстискват гроздовете в тоя свят. Питието има приятен вкус, напълно различен от отвратителния вкус на земното вино, не влияе лошо върху ума на човека, нито върху стомаха му и не причинява главоболие. Остава единствено развеселяващата му способност – без това да причинява опиянение, ни казва Ибн Касир.
Защото целта на виното е да носи забавлително удоволствие, тоест развеселяващо състояние, водещо до радост на душата – и това става чрез виното на Рая¹,
без да изчезва разсъдъкът на човека, от което той да става като животните и безумните хора.
Да добавим и трети класик коментатор – Ал-Куртуби (Кордобеца) от XIII век. В класическия си коментар той разсъждава и върху общата категория на плодовете в Коран 55:68: дали фурмите и дали наровете въобще са плодове, или пък са отделна категория ядива. Със сигурност обаче са специални – фурмата едновременно е подслаждащ плод и храна, докато нарът е хем плод, хем има лечебни свойства. А палмовите дървета в Рая имат стволове от зелен изумруд, прицветникът, който обгръща цветовете им, е от червено злато, листата им са дрехи, покривало за обитателите на Рая, плодовете им, тоест фурмите, са като големи грънци, по-бели от млякото, по-сладки от меда, по-меки от маслото и без костилки.
Небесните деликатеси като част от вечността и райското блаженство на праведните възбуждат както въображението на мюсюлмани, така и на не-мюсюлмани като неотменна част съответно от религиозната проповед и от разкази. Марко Поло от XIII век даже пресолява манджата (райската) с това си очакване, като говори за хашишините и мистериозния „Старец от планината“ при пътуването си през Персия.
„Алоадин“, казва той, ръководителят на ордена, е превърнал една затворена долина между две планини в градина, най-голямата и най-красивата, изпълнена с плодове, потоци с вино, мляко, мед и вода (разпознавате вече езика на Корана), павилиони и дворци, населени с най-красивите девойки на земята. Тъй като искал да накара всички да повярват, че това всъщност е Раят, изградил мястото според описанието на Пророка. И никой не е допускан там освен кандидат-хашишините, тоест убийци, изпращани да тероризират сунитските владетели, доколкото движението на Хасан ас-Сабах изповядва шиитския исмаилизъм.
Веднъж допуснати там, младежите изпиват отвара, която ги кара да заспят дълбок сън. След него те се събуждат, заобиколени от градини, храни, питиета и девойки, което създава впечатлението, че са в Рая. Старецът убеждава последователите си, че е пророк, а когато изпраща някого от убийците си навън, той отново го упоява, та хашишинът да се събуди в замъка, извън градината на удоволствията. Тогава „Алоадин“ му възлага убийствена мисия с обещанието, че ако я изпълни, ще се завърне в Рая. Този разказ на Марко Поло днес се възприема като измислен, но създава един от най-устойчивите образи за употреба на небесните удоволствия с пропагандна цел.
А пък в самата мюсюлманска традиция небесни ястия се появяват много често като част от изображенията на нощното пътешествие възнесение (ми‘радж) на Пророка до небето на гърба на създанието Бурак – крилат кон с женска глава.
„Какво е „гнойната вода“ (садид)?“, се пита например. Отговорът е толкова подробен, та чак на човек му се отщява не само да чете, ами и да си сипе една ракия. „Гнойната вода“ е течност, която се стича от кожата и месата на опичащите се в адския огън грешници, подобна на гной и кръв, и препраща към вече известните ни коранични стихове. Ако човек има търпение, може да открие и образователни видеа, като това по Шарджа ТВ от Емиратите. Там ни се напомня, че
храната в Рая има начало – и това е черният дроб на кита, – но няма край,
с други думи, не е като вурста от съмнителната немска песничка от 80-те години, според която „всичко има край, само вурстът има два“. И дробът е просто предястието, нещо леко, което се поднася преди основното блюдо за арабите. А земята е като една огромна питка хляб в деня на Възкресението според преданието на Пророка. Дано Аллах да ми даде, а и на вас за препитание храната и питието на Рая, завършва видеото. А пък аз ще добавя, употребявайте такива видеа отговорно и с мярка, че не знаете как може да ви се отрази отвъдното вино.
Очевидно в отвъдното нещата променят същностните си характеристики. Коприната, която иначе е забранена за мъже в тоя свят, там се оказва позволена. Шафранът, който е хем подправка, хем багрило и аромат, тук е забранен за мъже, ала в отвъдното е позволен. Виното е подобен случай. Тук може да ти докара наказание, ала там тече в реки, подобни на морета.
Възбраненото в този свят може да се окаже позволено в онзи.
Обаче накрая все пак не успявам да разбера дали в мюсюлманския Рай ще има свинска вратна пържола. Представям си как един Ат-Табари, Ибн Касир или Ал-Куртуби биха я описали. „Пържола (шарихат лахм) сочна, отрязана от врата на най-чистото прасе, защото свинята (ханзир) в Райската градина ще бъде чиста, бяла, красива, по-голяма от вол, ще яде само позволени неща, ще пасе трева по райските ливади и ще пие вода от благословените извори“.
Това, разбира се, е моя спекулация. Ако е рекъл Всевишният, за което арабският език има хубавия израз ин ша’ Аллах!, един ден ще открия отговора. А междувременно може да отнесем въпроса към някой от големите портали за фетви и да чакаме. Аллах знае най-добре, винаги заключават там.
1 Ибн Касир. Ал-бидайа уа-н-нихайа, Уизарат ал-аукаф уа-ш-шу’ун ал-исламийа. Катар, 2015, т. 17, с. 467.
В рубриката „Ориент кафе“ Атанас Шиников поднася любопитни теми, свързани не толкова с горещата политика, колкото с историята и културата на Близкия изток. А той, древен и днешен, е по-близко до нас и съвремието ни, отколкото си представяме.
Migrating Apache Kafka workloads to the cloud often involves managing complex replication infrastructure, coordinating application cutovers with extended downtime windows, and maintaining deep expertise in open-source tools like Apache Kafka’s MirrorMaker 2 (MM2). These challenges slow down migrations and increase operational risk. Amazon MSK Replicator addresses these challenges, enabling you to migrate your Kafka deployments (referred to as “external” Kafka clusters) to Amazon MSKExpress brokers with minimal operational overhead and reduced downtime. MSK Replicator supports data migration from Kafka deployments (version 2.8.1 or later) that have SASL/SCRAM authentication enabled – including Kafka clusters running on-premises, on AWS, or other cloud providers, as well as Kafka-protocol-compatible services like Confluent Platform, Avien, RedPanda, WarpStream, or AutoMQ when configured with SASL/SCRAM authentication.
In this post, we walk you through how to replicate Apache Kafka data from your external Apache Kafka deployments to Amazon MSK Express brokers using MSK Replicator. You will learn how to configure authentication on your external cluster, establish network connectivity, set up bidirectional replication, and monitor replication health to achieve a low-downtime migration.
How it works
MSK Replicator is a fully managed serverless service that replicates topics, configurations, and offsets from cluster to cluster. It alleviates the need to manage complex infrastructure or configure open-source tools.
Before MSK Replicator, customers used tools like MM2 for migrations. These tools lack bi-directional topic replication when using the same topic names, creating complex application architectures to consume different topics on different clusters. Custom replication policies in MM2 can allow identical topic names, but MM2 still lacks bidirectional offset replication because the MM2 architecture requires producers and consumers to run on the same cluster to replicate offsets. This created complex migrations that required either migrating consumers before producers or big-bang migrations migrating all applications at once. When customers run into issues during the migration, the rollback process is error-prone and introduces large amounts of duplicate message processing due to the lack of consumer group offset synchronization. These approaches create risk and complexity for customers that make migrations difficult to manage.
MSK Replicator addresses these problems by supporting bidirectional replication of data and enhanced consumer group offset synchronization. MSK Replicator copies topics and offsets from an external Kafka cluster to MSK, allowing you to preserve the same topic and consumer group names on both clusters. MSK Replicator also supports creating a second Replicator instance for bidirectional replication of both data and enhanced offset synchronization, allowing producers and consumers to run independently on different Kafka clusters. Data published or consumed on the Amazon MSK cluster will be replicated back to the external cluster by the second Replicator. This feature works when producers and consumers are migrated regardless of order without worrying about dependencies between applications.
Because MSK Replicator provides bidirectional data replication and enhanced consumer group offset synchronization, you can move producers and consumers at your own pace without data loss. This reduces migration complexity, allowing you to migrate applications between your external Kafka cluster and Amazon MSK regardless of order. If you run into problems during the migration, enhanced offset synchronization allows you to roll back changes by moving applications back to the external Kafka cluster, where they restart from the latest checkpoint from the Amazon MSK cluster.
For example, consider three applications:
The “Orders” application, which accepts incoming orders and writes them to the orders Kafka topic
The “Order status” application, which reads from the “orders” Kafka topic and writes status updates to the order_status topic
The “Customer notification” application, which reads from the order_status topic and notifies customers when status changes
MSK Replicator enables these applications to be migrated between an on-premises Apache Kafka cluster and an Amazon MSK Express cluster with low downtime and no data loss, regardless of order. The “Order status” application can migrate first, receive orders from the on-premises “Orders” application, and send status updates to the on-premises “Customer notification” application. If issues arise during the migration, the “Order status” application can roll back to the on-premises cluster and its consumer group offsets for the orders topic will be ready for it to pick up from where it left off on the Amazon MSK cluster.
MSK Replicator supports data distribution across hybrid and multi-cloud environments for analytics, compliance, and business continuity. It is also configured for disaster recovery scenarios where Amazon MSK Express serves as a resilient target for your external Kafka clusters.
MSK Replicator supports Kafka deployments running version 2.8.1 or later as a source, including 3rd party managed Kafka services, self-managed Kafka, and on-premises or third-party cloud-hosted Kafka. MSK Replicator automatically handles data transfer, uses SASL/SCRAM authentication with SSL encryption, and maintains consumer group positions across both clusters. If you do not use SASL/SCRAM today, this can be configured as a new listener used for MSK Replicator allowing current clients to use their existing authentication mechanisms alongside MSK Replicator.
Prerequisites
To follow along with this walkthrough, you need the following resources in place:
AWS Secrets Manager configured to store your SASL/SCRAM credentials for the external cluster so that MSK Replicator can securely retrieve them at runtime
You can set up network connectivity between your external Kafka cluster and your AWS VPC using methods such as AWS Direct Connect for dedicated network connections, AWS Site-to-Site VPN for encrypted connections over the internet, and AWS VPC peering or AWS Transit Gateway for connections between AWS VPCs. Verify that IP routing and DNS resolution are properly configured between your external cluster and AWS.
To verify IP routing and DNS resolution, connect to your external Kafka cluster from inside of your VPC by using the Kafka CLI to list topics on the external cluster. If you can list topics from your VPC using the Kafka CLI, this means DNS resolution and IP routing are working successfully. If it fails, work with your network admins to troubleshoot network connectivity issues.
Step 2: Configure external cluster
In this step, you will set up authentication on your external Kafka cluster and store the credentials in AWS Secrets Manager so that MSK Replicator can connect securely.
Configure authentication
Using the external cluster admin user, configure SASL/SCRAM authentication for MSK Replicator using SHA-256 or 512 on your external Kafka cluster. Create a SASL/SCRAM user for MSK Replicator and give the user the following ACL permissions:
AWS Secrets Manager stores your SASL/SCRAM credentials securely so that MSK Replicator can retrieve them at runtime. The secret must use JSON format and have the following keys:
username – The SCRAM username that you configured in the authentication step above
password – The SCRAM password that you configured in the authentication step above
certificate – The public root CA certificate (the top-level certificate authority that issued your cluster’s TLS certificate) and the intermediate CA chain (intermediate certificates between the root and your cluster’s certificate), used for SSL handshakes with the external cluster
Optionally, you may create separate secrets for SCRAM credentials and the SSL certificate. This approach is useful when secrets for SCRAM credentials and certificates are provisioned in different stages, such as in Infrastructure as Code (IaC) pipelines.
Retrieve the cluster ID
As the admin user, use the Kafka CLI tools to retrieve the cluster ID of your external cluster. Run the following command, replacing your-broker-host:9096 with the address of one of your external cluster’s bootstrap servers:
The command returns a cluster ID string such as lkc-abc123. Take note of this value because you will need it when creating the replicator in Step 4.
Step 3: Create your MSK Express target cluster
With your external cluster configured, you can now set up the target. Create an Amazon MSK Express cluster with IAM authentication enabled. Make sure that the cluster is in subnets that have access to AWS Secrets Manager endpoints. See Get started using Amazon MSK for more information on creating an MSK cluster.
Step 4: Create the replicator
Now that both clusters are ready, you can connect them by setting up the MSK Replicator with the appropriate IAM role and replication configuration.
Set up an IAM role for MSK Replicator
MSK Replicator needs an IAM role to interact with your MSK Express cluster and retrieve secrets. Set up a service execution IAM role with a trust policy allowing kafka.amazonaws.com and attach the AWSMSKReplicatorExecutionRole permissions policy. Take note of the role ARN for creating the replicator.
Create and attach a policy for accessing your Secrets Manager secrets and reading/writing data in your MSK cluster. See Creating roles and attaching policies (console) for more information on creating IAM roles and policies.
The following is an example policy for reading and writing data to your MSK cluster and reading KMS-encrypted Secrets Manager secrets:
The kafka-clusters.json file defines the source and target Kafka cluster connection information, replication-info.json specifies which topics to replicate and how to handle consumer group offset synchronization, and log-delivery.json specifies the CloudWatch logging configuration. The following tables describe the required parameters:
CLI inputs:
CLI Parameter
Description
Example
replicator-name
The name of the replicator
external-to-msk
service-execution-role-arn
The ARN for the service execution IAM role you created
arn:aws:iam::123456789012:role/MSKReplicatorRole
kafka-clusters
The Kafka cluster connection info
See below
replication-info-list
The replication configuration
See below
log-delivery
The logging configuration
See below
Key kafka-clusters.json inputs:
CLI Parameter
Description
Example
ApacheKafkaClusterId
The cluster ID retrieved in Step 2
lkc-abc123
RootCaCertificate
The Secrets Manager ARN containing the public CA certificate and intermediate CA chain
The list of topics to replicate (use [“.*”] for all topics)
[“my-topic”]
ConsumerGroupsToReplicate
The list of consumer groups to replicate
[“my-group”]
StartingPosition
The point in the Kafka topics to begin replication from (either EARLIEST or LATEST)
EARLIEST
ConsumerGroupOffsetSyncMode
Whether or not to use enhanced bidirectional consumer group offset synchronization
ENHANCED
Note that startingPosition is set to EARLIEST in the configuration below, which means the replicator begins reading from the oldest available offset on each topic. This is the recommended setting for migrations to avoid data loss.
Key log-delivery.json inputs:
CLI Parameter
Description
Example
Enabled
Allows you to enable CloudWatch logging
true
LogGroup
The CloudWatch logs log group name to log to
/msk/replicator/my-replicator
Additional log delivery methods for Amazon S3 and Amazon Data Firehose are supported. In this post, we use CloudWatch logging.
The configs should look like the following for external to MSK replication.
Configure bidirectional replication from MSK to the external cluster
To enable bidirectional replication, create a second replicator that replicates in the opposite direction. Use the same IAM role and network configuration from Step 4, but swap the source and target. Replace SourceKafkaClusterId with TargetKafkaClusterId and TargetKafkaClusterArn with SourceKafkaClusterArn in a new msk-to-external-replication-info.json file:
Monitor your replication using Amazon CloudWatch metrics. Three key metrics to understand are MessageLag, SumOffsetLag, and ReplicationLatency. MessageLag measures how far behind the replicator is from the external cluster in terms of messages not yet replicated, while SumOffsetLag measures how far behind a consumer group is from the latest message in a topic. ReplicationLatency is the amount of latency between the source and target clusters in data replication. When the three reach a sustained low level, your clusters are fully synchronized for both data and consumer group offsets.
To troubleshoot MSK Replicator replication or errors, use the CloudWatch logs to get more details about the health of the replicator. MSK Replicator logs status and troubleshooting information which can be helpful in diagnosing issues like connectivity, authentication, and SSL errors.
Note that the replication is asynchronous, so there will be some lag during replication. The lag will reach zero once a client is shut down during migration to the target cluster. This takes about 30 seconds under normal operations, allowing a low downtime migration without data loss. If your lag is continually increasing or does not reach a sustained low level, this indicates that you have insufficient partitions for high-throughput replication. Refer to Troubleshoot MSK Replicator for more information on troubleshooting replication throughput and lag.
Key metrics include:
MessageLag – Monitors the sync between the MSK Replicator and the source cluster. MessageLag indicates the lag between the messages produced to the source cluster and messages consumed by the replicator. It is not the lag between the source and target cluster.
ReplicationLatency – Time taken for records to replicate from source to target cluster (ms)
ReplicatorThroughput – Average number of bytes replicated per second
ReplicatorFailure – Number of failures the replicator is experiencing
Your applications are ready to migrate when the following conditions are met. For most workloads, you should expect these metrics to stabilize within a few hours of starting replication. High-throughput clusters may take longer depending on topic volume and partition count.
ReplicatorFailure = 0
ConsumerGroupOffsetSyncFailure = 0
KafkaClusterPingSuccessCount = 1 for both source and target clusters
MessageLag < 1,000
Your sustained lag may be lower or higher depending on your throughput per partition, message size, and other factors
Sustained high message lag usually indicates insufficient partitions for high-throughput replication
ReplicationLatency < 90 seconds
Your sustained latency may be lower or higher depending on your throughput per partition, message size, and other factors
Sustained high latency usually indicates insufficient partitions for high-throughput replication
SumOffsetLag is at a sustained low level on both clusters
Offset values on the two clusters may not be numerically identical.
MSK Replicator translates offsets between clusters so that consumers resume from the correct position, but the raw offset numbers can differ due to how offset translation works. What matters is that SumOffsetLag is at a sustained low level.
If ConsumerGroupCount is zero or does not match the expected count, then there is an issue in the Replicator configuration or a permissions issue preventing consumer group synchronization
Migrating your applications
With bidirectional consumer offset synchronization, you can migrate your producers and consumers regardless of order. Start by monitoring replication metrics until they reach the target values described in the previous section. Then migrate your applications (producers or consumers) to use the MSK Express cluster endpoints and verify that they are producing and consuming as expected. If you encounter issues, you can roll back by switching applications back to the external cluster. The consumer offset synchronization makes sure that your applications resume from their last committed position regardless of which cluster they connect to.
For a comprehensive, hands-on walkthrough of the end-to-end migration process, explore the MSK Migration Workshop, which provides step-by-step guidance for migrating your Kafka workloads to Amazon MSK.
Security considerations
MSK Replicator uses SASL/SCRAM authentication with SSL encryption for secure data transfer between your external cluster and AWS. The solution supports both publicly trusted certificates and private or self-signed certificates. Credentials are stored securely in AWS Secrets Manager, and the target MSK Express cluster uses IAM authentication for access control.
When configuring security, keep the following in mind:
Make sure that the IAM role you create in Step 4 follows the principle of least privileges. Only attach AWSMSKReplicatorExecutionRole and an IAM policy for Secrets Manager with least-privileges access to read secret values and avoid adding broader permissions.
Verify that your Secrets Manager secret is encrypted with an AWS KMS key that the MSK Replicator service execution role has permission to decrypt.
Confirm that the security groups assigned to MSK Replicator allow outbound traffic to your external cluster’s broker ports (typically 9096 for SASL/SCRAM with TLS) and to the MSK Express cluster.
Rotate your SASL/SCRAM credentials periodically and update the corresponding Secrets Manager secret. MSK Replicator picks up the new credentials automatically on the next connection attempt.
Under the AWS shared responsibility model, AWS is responsible for securing the underlying infrastructure that runs MSK Replicator, including the compute, storage, and networking resources. You are responsible for configuring authentication mechanisms (SASL/SCRAM), managing credentials in AWS Secrets Manager, configuring network security (security groups and VPC settings), implementing IAM policies following least privilege, and rotating credentials. For more information, see Security in Amazon MSK in the Amazon MSK Developer Guide.
Cleanup
To avoid ongoing charges, delete the resources you created during this walkthrough. Start by deleting the replicators first, because they depend on the other resources:
After both replicators are deleted, you can remove the following resources if they were created solely for this walkthrough:
The MSK Express cluster (deleting a cluster also removes its stored data, so verify that your applications have fully migrated before proceeding)
The Secrets Manager secrets containing your SASL/SCRAM credentials and certificates
The IAM role and policies created for MSK Replicator
You can verify that a replicator has been fully deleted by running aws kafka list-replicators and confirming it no longer appears in the output.
Conclusion
Amazon MSK Replicator simplifies the process of migrating to Amazon MSK Express brokers and establishes hybrid Kafka architectures. The fully managed service alleviates the operational complexity of managing replication while bidirectional consumer offset synchronization enables flexible, low-risk application migration.
Next Steps
To get started using MSK Replicator to migrate applications to MSK Express brokers, use the MSK Migration Workshop for a hands-on, end-to-end migration walkthrough. The Amazon MSK Replicator documentation includes detailed configuration details to help configure MSK Replicator for your use case. From there, use MSK Replicator to migrate your Apache Kafka workloads to MSK Express broker.
Once your migration is complete, consider exploring multi-region replication patterns for disaster recovery, or integrating your MSK Express cluster with AWS analytics services such as Amazon Data Firehose and Amazon Athena. If you need help planning your migration, reach out to your AWS account team, AWS Support or AWS Professional Services.
Git maintainer Junio Hamano has announced
Git 2.54.0, which includes contributions from 137 people; 66 of those
people are first-time contributors to the project. Changes include the
addition of Git history rewriting, Git’s web interface (gitweb)
“has been taught to be mobile friendly“, and much more. See the
announcement for all improvements, additions, and bug fixes. Hamano
is now taking a short break:
I will go offline for a couple of weeks starting this evening,
hopefully after updating ‘next’ and possibly also pushing out the
first batch of the new cycle. There is no designated interim
maintainer this time, but I trust that the community can self
organize during my absense, if the shape of the release and the tree
turns out to be super bad ;-).
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
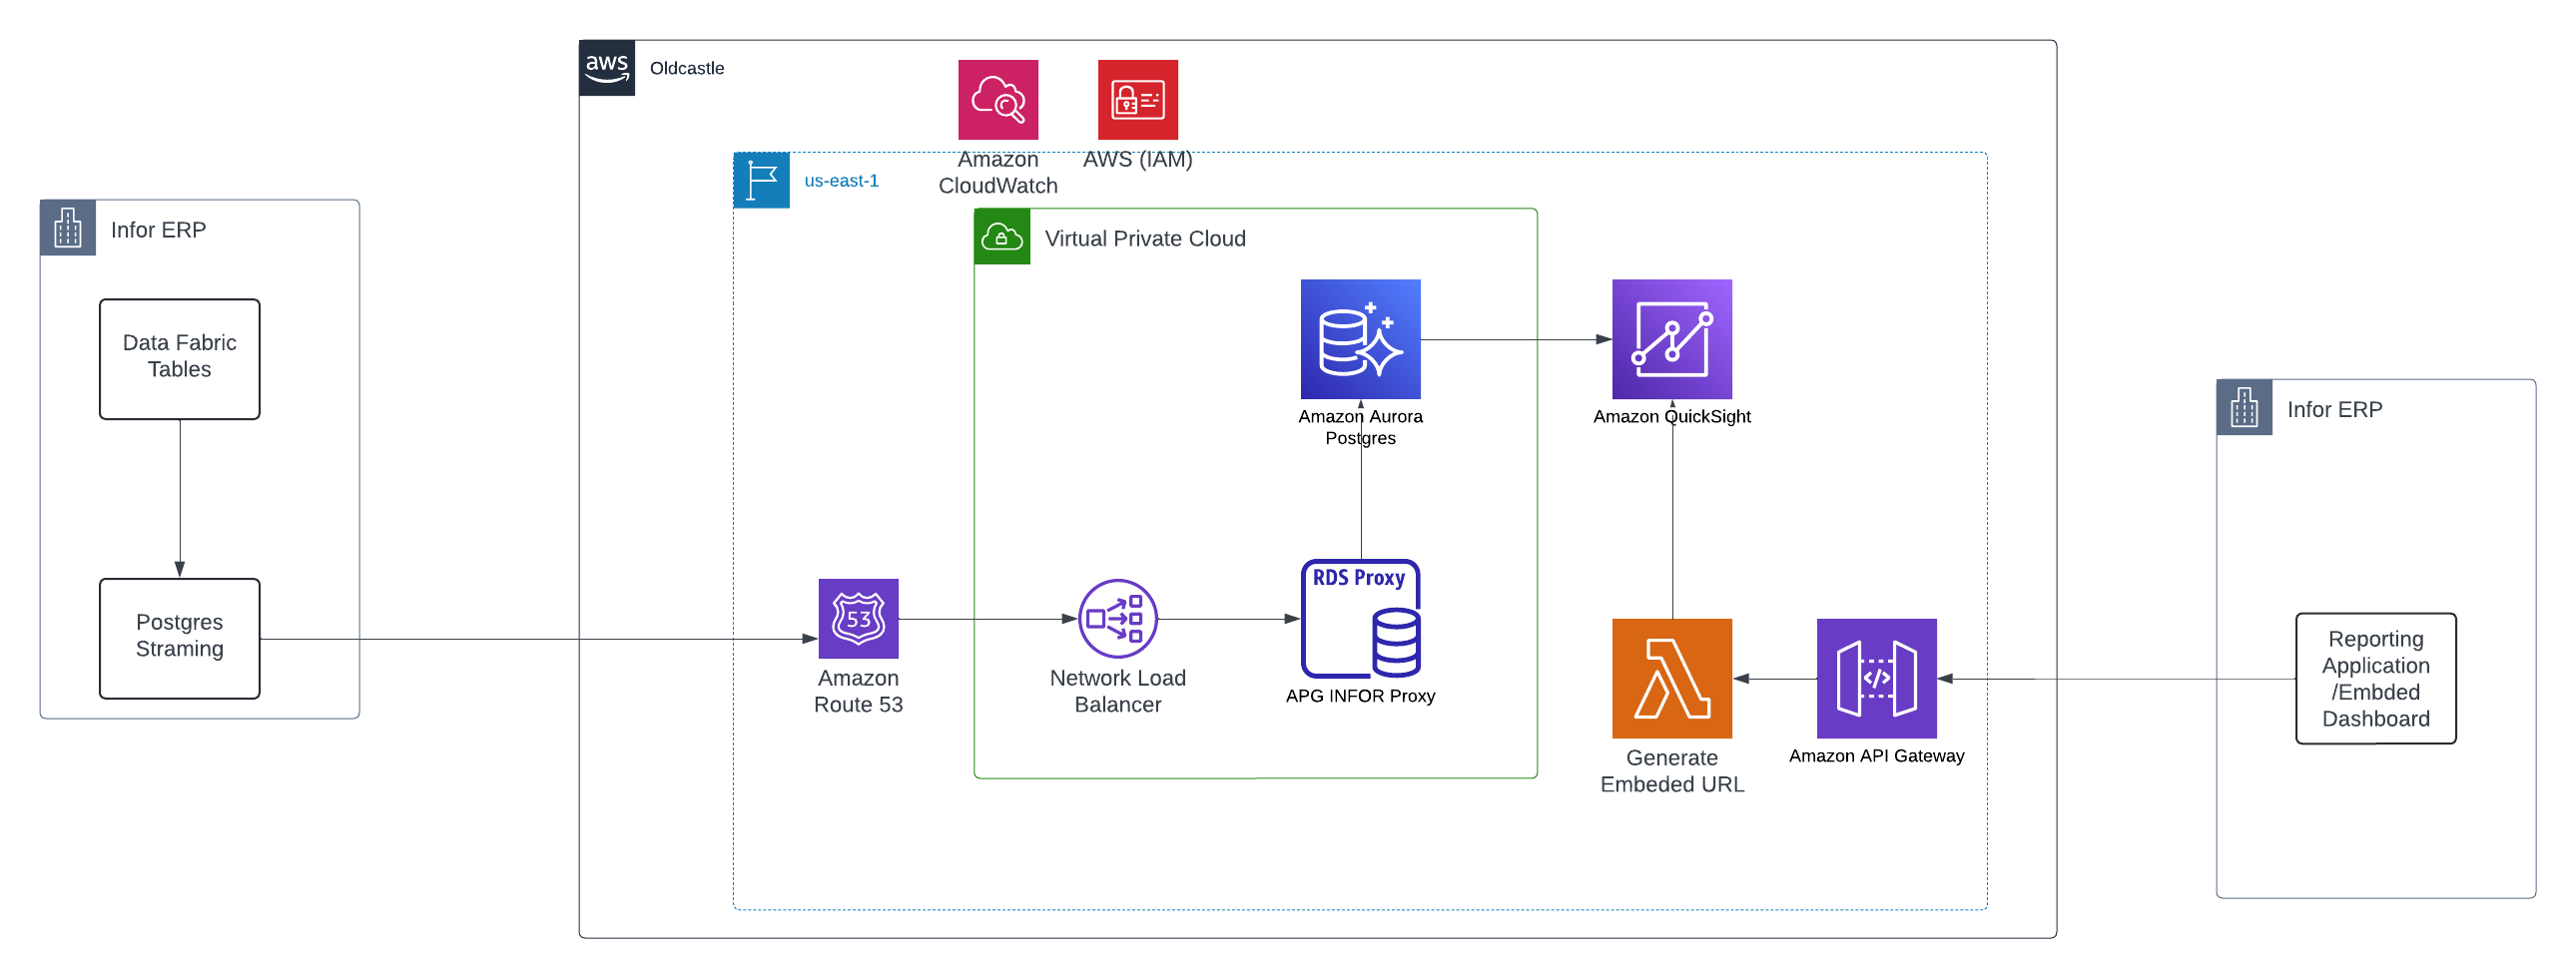
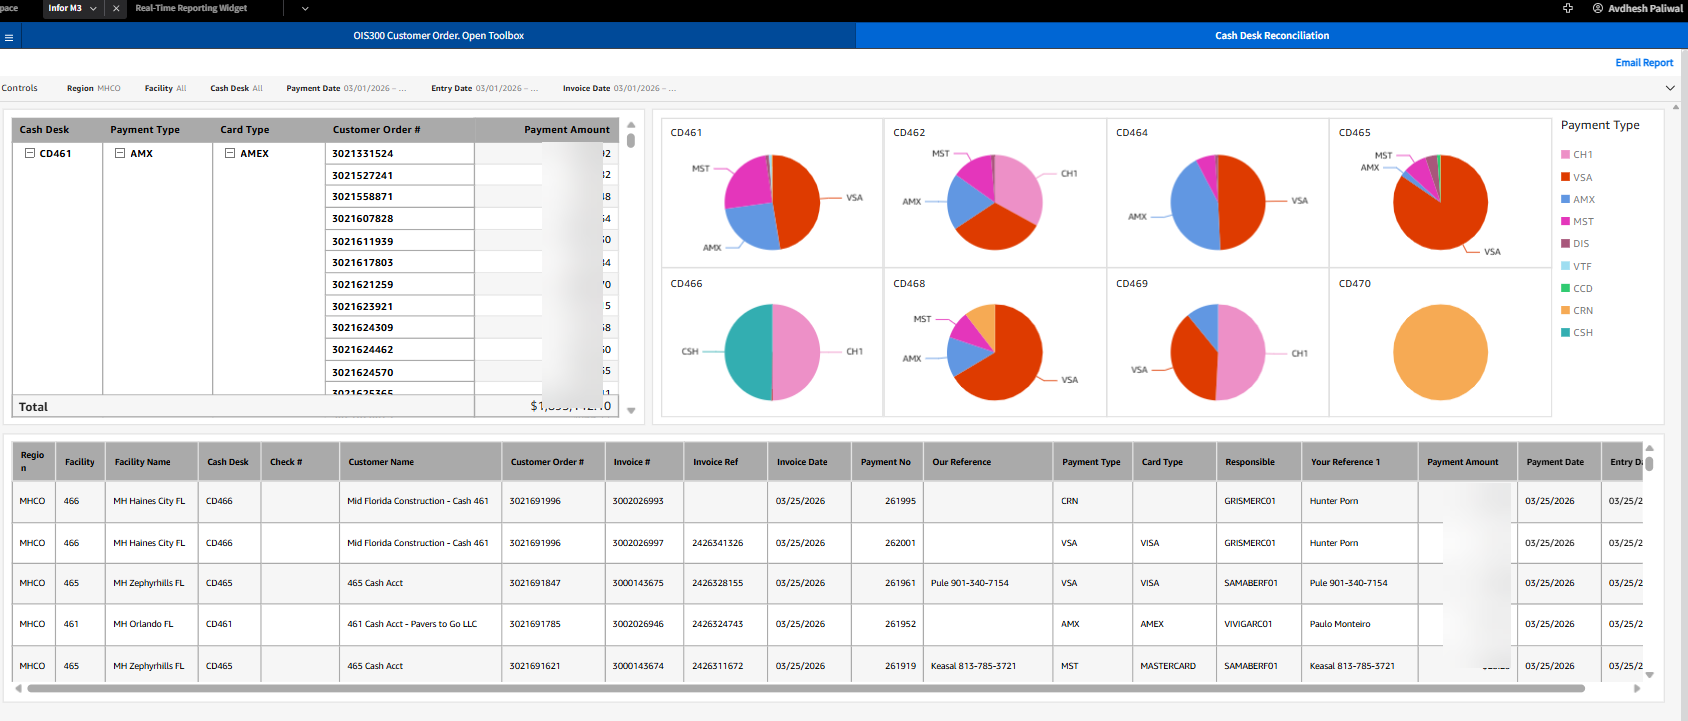
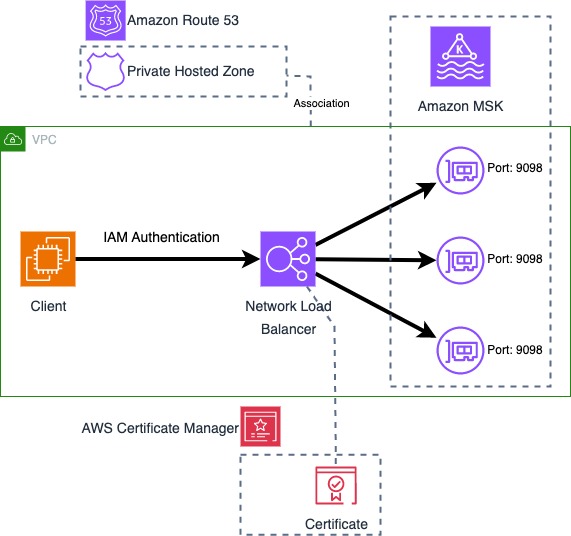
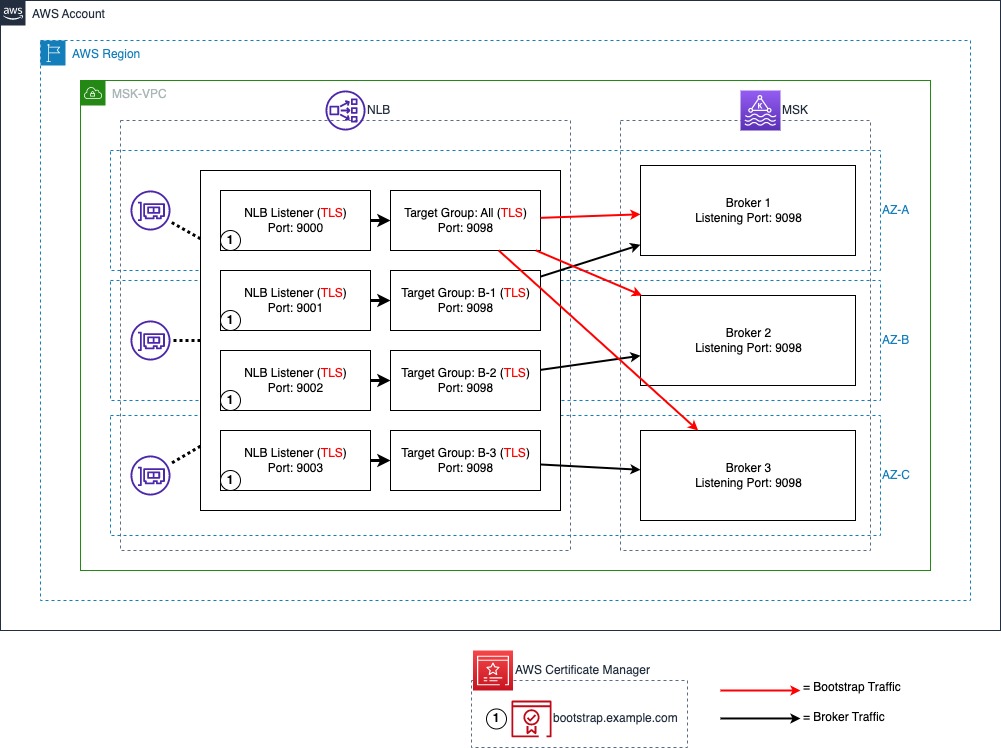
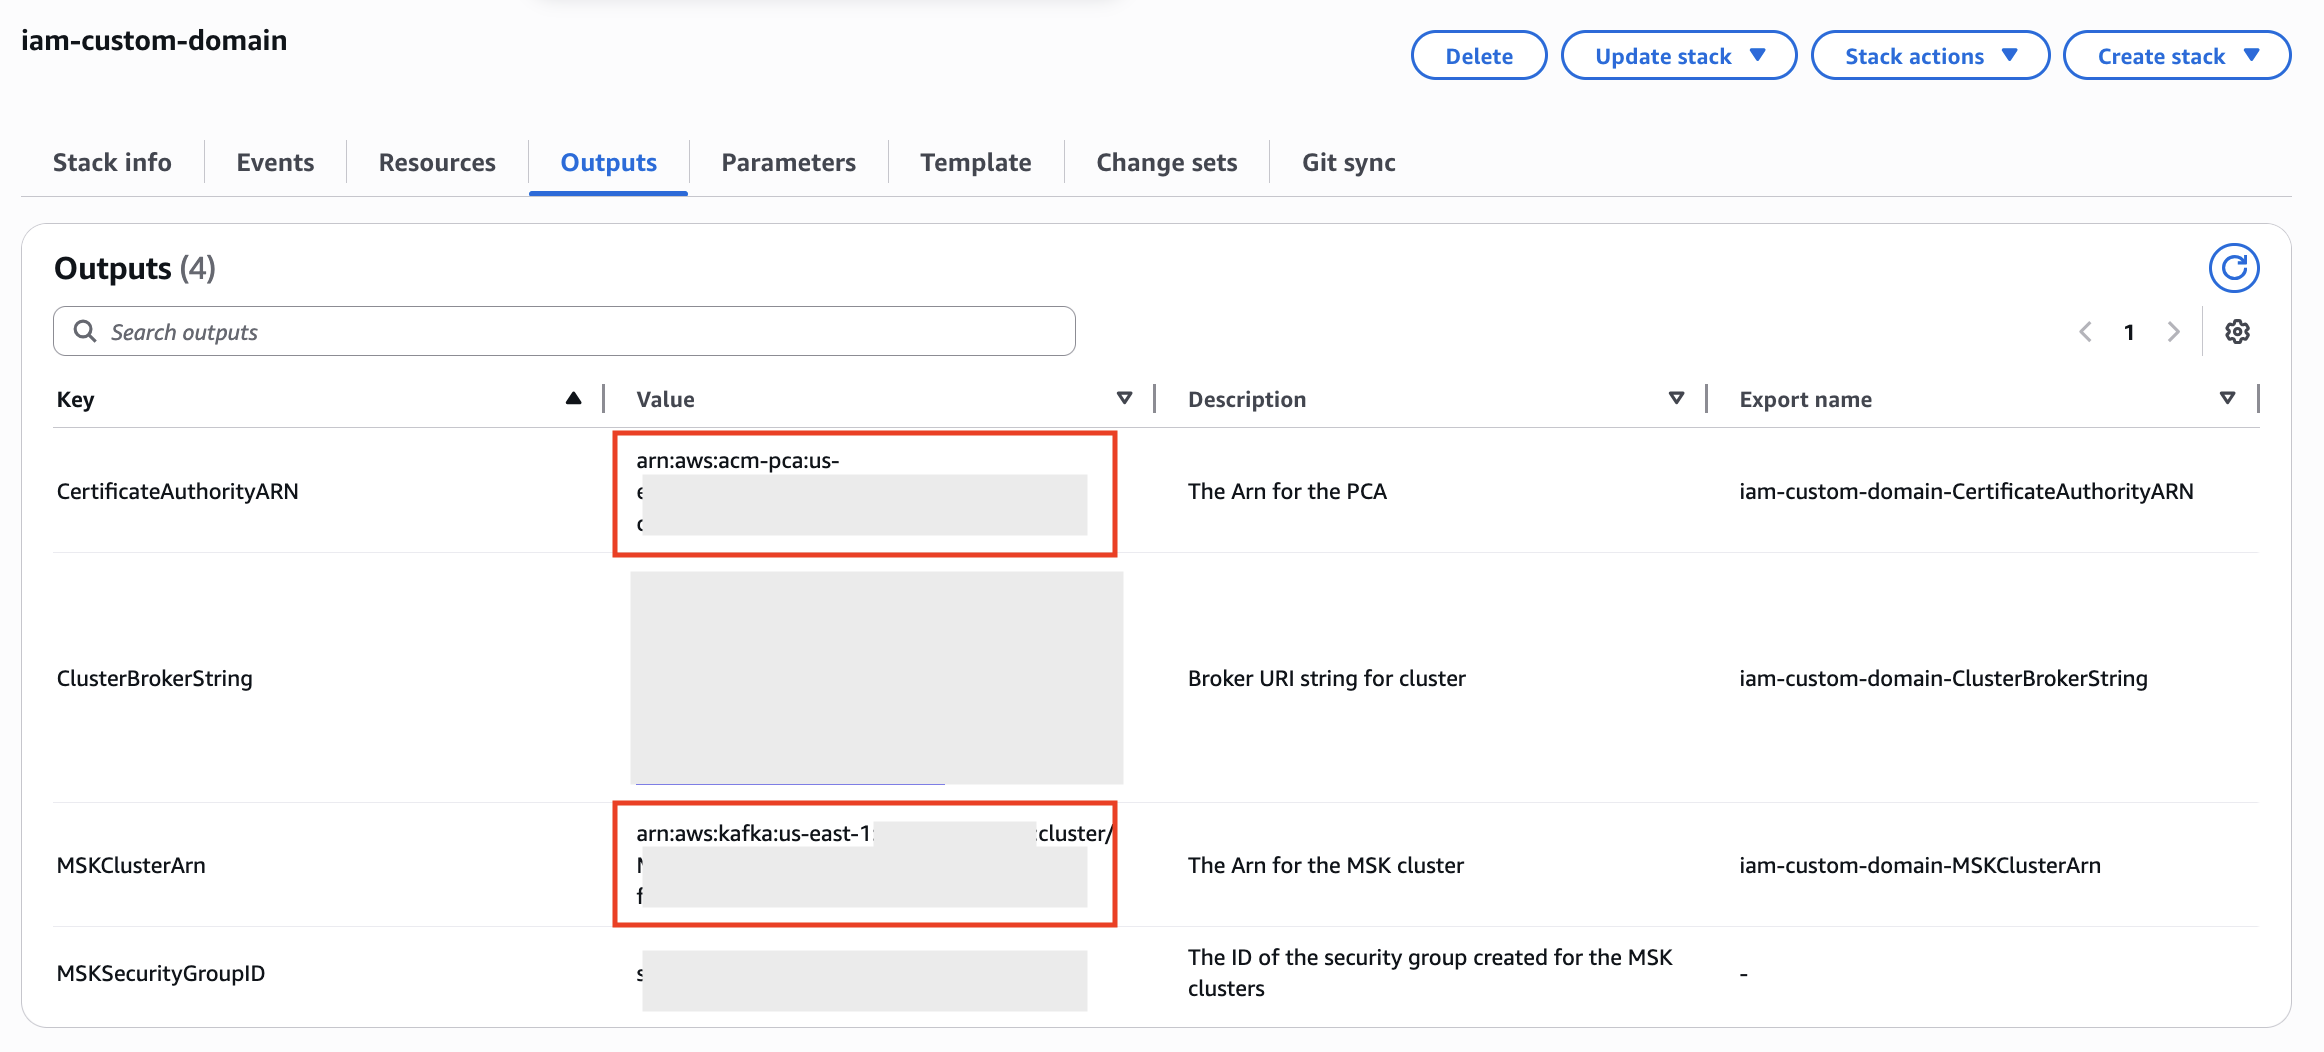
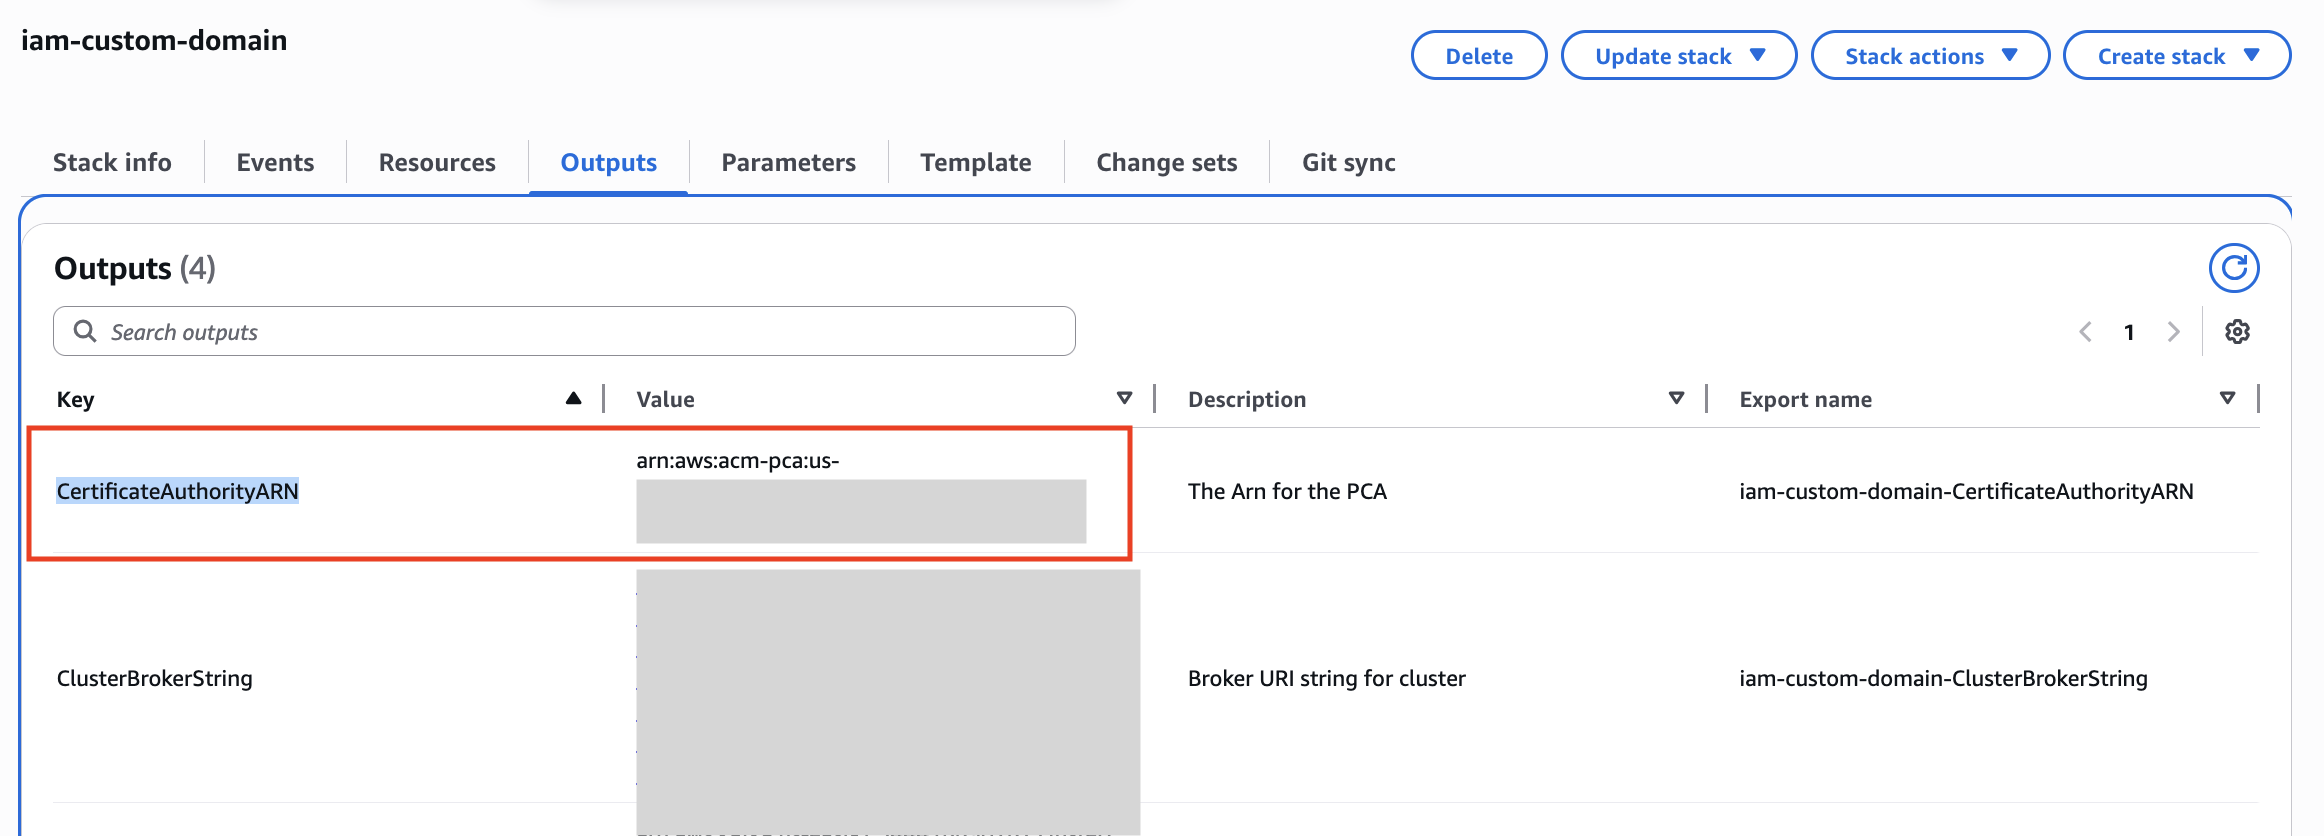 We’re using the default Java truststore which uses the password