Amazon Inspector security researchers have identified and reported over 150,000 packages linked to a coordinated tea.xyz token farming campaign in the npm registry. This is one of the largest package flooding incidents in open source registry history, and represents a defining moment in supply chain security, far surpassing the initial 15,000 packages reported by Sonatype researchers in April 2024. Through a combination of advanced rule-based detection and AI, the research team uncovered a self-replicating attack pattern where threat actors automatically generate and publish packages to earn cryptocurrency rewards without user awareness, revealing how the campaign has expanded exponentially since its initial identification.
This incident demonstrates both the evolving nature of threats where financial incentives drive registry pollution at unprecedented scale, and the critical importance of industry-community collaboration in defending the software supply chain. The Amazon Inspector team’s capability to detect subtle, non-traditional threats through innovative detection methodologies, combined with rapid collaboration with the Open Source Security Foundation (OpenSSF) to assign malicious package identifiers (MAL-IDs) and coordinate response, provides a blueprint for how security organizations can respond swiftly and effectively to emerging attack vectors. As the open source community continues to grow, this case serves as both a warning that new threats will emerge wherever financial incentives exist, and a demonstration of how collaborative defense can help address supply chain attacks.
Detection
On October 24, 2025, Amazon Inspector security researchers deployed a new detection rule—paired with AI—to identify additional suspicious package patterns in the npm registry. Within days, the system began flagging packages linked to the tea.xyz protocol—a blockchain-based system designed to reward open source developers.
By November 7, the researchers flagged thousands of packages and began investigating what appeared to be a coordinated campaign. The next day, after validating the evaluation results and analyzing the patterns, they reached out to OpenSSF to share their findings and coordinate a response. With OpenSSF’s review and alignment, Amazon Inspector security researchers began systematically submitting discovered packages to the OpenSSF malicious packages repository, with each package receiving a MAL-ID within 30 minutes. The operation continued through November 12, ultimately uncovering over 150,000 malicious packages.
Here’s what the investigation revealed:
Over 150,000 packages linked to the tea.xyz token farming campaign
Self-replicating automation that creates packages without legitimate functionality
Systematic inclusion of tea.yaml files that link packages to blockchain wallet addresses
Coordinated publishing activity across multiple developer accounts
Unlike traditional malware, these packages do not contain overtly malicious code. Instead, they exploit the tea.xyz reward mechanism by artificially inflating package metrics through automated replication and dependency chains, allowing threat actors to extract financial benefits from the open source community.
Token farming as a new attack vector
This campaign represents a concerning evolution in supply chain security. Although the packages might not steal credentials or deploy ransomware, they pose significant risks:
Registry pollution – The npm registry is flooded with low-quality, non-functional packages that obscure legitimate software and degrade trust in the open source community.
Resource exploitation – Registry infrastructure, bandwidth, and storage are consumed by packages created solely for financial gain rather than genuine contribution.
Precedent for abuse – The success of this campaign could inspire similar exploitation of other reward-based systems, normalizing automated package generation for financial gain.
Supply chain risk – Even packages that seem benign can add unnecessary dependencies, potentially introducing unexpected behaviors or creating confusion in dependency resolution.
Collaboration with OpenSSF: rapid response
The collaboration between Amazon Inspector security researchers and OpenSSF led to swift action and benefits such as the following:
Immediate threat intelligence sharing – The researchers’ findings were shared with OpenSSF’s malicious packages repository, providing the community with comprehensive threat data.
MAL-ID assignment – OpenSSF rapidly assigned MAL-IDs to the detected packages, enabling community-wide blocking and remediation. Average time of assignment was 30 minutes.
Coordinated disclosure – Both organizations worked together to inform the broader open source community about the threat.
Enhanced detection standards – Insights from this campaign are informing improved detection capabilities and policy recommendations across the open source security community.
This collaboration exemplifies how industry leaders and community organizations can work together to help protect software supply chains. The rapid assignment of MAL-IDs demonstrates OpenSSF’s commitment to maintaining the integrity of open source registries, while the researchers’ detection work and threat intelligence provide the advanced insights needed to stay ahead of evolving attack patterns.
Technical details: how the researchers detected the campaign
Amazon Inspector security researchers used a combination of rule-based detection paired with AI-powered techniques to uncover this campaign. The researchers developed pattern matching rules to identify suspicious characteristics such as the following:
Presence of tea.yaml configuration files
Minimal or cloned code with no original functionality
Predictable naming patterns and automated generation signatures
Circular dependency chains between related packages
By monitoring publishing patterns, the researchers revealed coordinated campaigns that used automated tooling to create packages at automated speeds.
How to respond to these types of events
You should follow your standard incident response process for active incidents to resolve the issue.
To sweep your development environment, we recommend the following steps:
Use Amazon Inspector – Check the findings for packages that are linked to tea.xyz token farming and follow recommended remediation.
Greg Kroah-Hartman has announced the release of the 6.17.8 and 6.12.58 stable kernels. Each contains an
important set of fixes. Users are advised to upgrade.
On October 6, 2025, the cyber deception company Defused published a proof-of-concept exploit on social media that was captured by one of their Fortinet FortiWeb Manager honeypots. FortiWeb is a Web Application Firewall (WAF) product that is designed to detect and block malicious traffic to web applications. Exploitation of this new vulnerability, now tracked as CVE-2025-64446, allows an attacker with no existing level of access to gain administrator-level access to the FortiWeb Manager panel and websocket command-line interface. Rapid7 has tested the latest FortiWeb version 8.0.2 and observed that the existing public proof-of-concept exploit does not work. However, the exploit does work against earlier versions, including version 8.0.1, which was released in August, 2025.
Based on the information circulated by Defused, this new vulnerability is claimed to have been exploited in the wild in October, 2025. On November 14, 2025, Fortinet PSIRT published CVE-2025-64446 and an official advisory for the critical vulnerability, which holds a CVSS score of 9.1. Organizations running versions of Fortinet FortiWeb that are listed as affected in the advisory are advised to remediate this vulnerability on an emergency basis, given that exploitation has been occurring since October in targeted attacks, and broad exploitation will likely occur in the coming days. A Metasploit module for CVE-2025-64446 is available here, and security firm watchTowr has published a technical analysis. CISA’s KEV catalog has been updated to include CVE-2025-64446.
It’s unclear whether the FortiWeb release cycle intentionally included a silent patch for this vulnerability or merely coincidentally included changes that broke the existing exploit.
On November 18, 2025, Fortinet published a new advisory for CVE-2025-58034. This new vulnerability is an authenticated command injection affecting FortiWeb. Fortinet has indicated CVE-2025-58034 has also been exploited in-the-wild, and CISA’s KEV catalog has been updated to include this new vulnerability. It is not clear at this time if both CVE-2025-64446 and CVE-2025-58034 have been exploited in-the-wild together as an exploit chain.
This blog post will be updated as new developments arise.
Rapid7 observations
On November 6, 2025, Rapid7 Labs observed that an alleged zero-day exploit targeting FortiWeb was published for sale on a popular black hat forum. While it is not clear at this time if this is the same exploit as the one described above, the timing is coincidental.
⠀
Mitigation guidance
On November 14, 2025, Fortinet published an advisory that outlines remediation steps and workaround mitigations for CVE-2025-64446. According to Fortinet, the following versions are affected, and the fixed versions for each main release branch are also listed:
Versions 8.0.0 through 8.0.1 are vulnerable, 8.0.2 and above are fixed.
Versions 7.6.0 through 7.6.4 are vulnerable, 7.6.5 and above are fixed.
Versions 7.4.0 through 7.4.9 are vulnerable, 7.4.10 and above are fixed.
Versions 7.2.0 through 7.2.11 are vulnerable, 7.2.12 and above are fixed.
Versions 7.0.0 through 7.0.11 are vulnerable, 7.0.12 and above are fixed.
In cases where immediate upgrades are not possible, the advisory states the following: “Disable HTTP or HTTPS for internet facing interfaces. Fortinet recommends taking this action until an upgrade can be performed. If the HTTP/HTTPS Management interface is internally accessible only as per best practice, the risk is significantly reduced.”
Exploitation behavior
When testing the public exploit against a target FortiWeb device, the target application’s differing responses between versions 8.0.1 and 8.0.2 are included below.
Against version 8.0.1, the application returns the following response for a successful exploitation attempt, in which a new malicious local administrator account “hax0r” was created:
Exposure Command, InsightVM and Nexpose customers can assess their exposure to CVE-2025-64446 with an unauthenticated vulnerability check available in the November 14 content release. Please note that the “SAFE” check mode needs to be disabled while running scans to ensure the check runs successfully.
Customers running FortiWeb release branches 8.0, 7.2, or 7.0 can leverage the existing CVE-2025-64446 check to establish exposure to the medium-severity authenticated vulnerability CVE-2025-58034. Those running FortiWeb release branches 7.6 or 7.4 should manually verify that the 7.6.6 and 7.4.11 patches, respectively, are in place for CVE-2025-58034.
Intelligence Hub
Customers leveraging Rapid7’s Intelligence Hub can track the latest developments surrounding CVE-2025-64446, including a Sigma rule and IOCs of IP addresses attempting to exploit this vulnerability.
Updates
November 14, 2025: The blog post has been updated to reflect the newly-published official advisory and CVE identifier, the availability of vulnerability checks and a Metasploit module for customer testing, the CISA KEV addition, and a published technical analysis.
November 17, 2025: The Rapid7 customers section has been updated to add Intelligence Hub coverage, and clarify that vulnerability checks were shipped on Nov 14, 2025.
November 19, 2025: The Overview section has been updated to reference the newly published vulnerability, CVE-2025-58034. The Rapid7 customers section has been updated to add expected coverage availability for CVE-2025-58034.
November 19, 2025: The Rapid7 customers section has been updated with CVE-2025-58034 coverage information for supported FortiWeb release branches.
The Google Security Blog has a
new post on just how well the use of Rust is working out for the
Android project.
We adopted Rust for its security and are seeing a 1000x reduction
in memory safety vulnerability density compared to Android’s C and
C++ code. But the biggest surprise was Rust’s impact on software
delivery. With Rust changes having a 4x lower rollback rate and
spending 25% less time in code review, the safer path is now also
the faster one.
It’s that time of year again — AWS re:Invent is here! At re:Invent, bold ideas come to life. Get a front-row seat to hear inspiring stories from AWS experts, customers, and leaders as they explore today’s most impactful topics, from data analytics to AI.
For all the data enthusiasts and professionals, we’ve curated a comprehensive guide to every analytics session to help you plan your perfect agenda. Make sure to secure your seat early for must-attend sessions via the attendee portal.
Pro tip: Even if a session shows as fully reserved, we encourage you to join the walk-up line at the session location. Based on previous years’ experiences, additional seats often become available due to no-shows or last-minute schedule changes. The walk-up line operates on a first-come, first-served basis, and many attendees have successfully accessed their desired sessions this way. Just be sure to arrive at least 15 minutes before the session starts for the best chance of getting a seat.
Can’t make it in person? No problem — grab a free virtual pass to stream live sessions from anywhere.
And don’t forget to stop by the AWS Kiosk in the AWS Village Expo for AWS Analytics, Amazon SageMaker, Amazon OpenSearch Service and AWS Messaging and Streaming services! See live demos of analytics services, meet AWS experts, get your toughest data questions answered, explore the latest launches, join our data trivia, and even win exclusive AWS-authored books and many more swags.
Emerging trends, ranging from Open Table Formats (OTF) to agentic infrastructure, are rapidly changing how humans and applications interact with analytics to drive mission-critical business decisions. Join Mai-Lan Tomsen Bukovec, VP of AWS Technology, to explore emerging trends, the evolution of analytics engines and applications, and how to future-proof your data foundation for the rapidly changing landscape of analytics at scale. Learn how AWS is transforming data and analytics services to lead in optimized data storage, querying, streaming, processing, and governance – for both human users and agentic infrastructure.
Breakouts
Dive into cutting-edge topics with re:Invent breakout sessions. These immersive, hour-long lectures are led by AWS experts, customers, offering you unparalleled insights and knowledge in a concise format. Whether you’re exploring the latest in cloud technology, AWS Analytics advancements, or industry-specific solutions, these sessions are designed to expand your horizon and inspire your next big idea.
Monday, Dec 1
Tuesday, Dec 2
Wednesday, Dec 3
Thursday, Dec 4
8:30 AM – 9:30 AM PST | Venetian | Level 3 | Lido 3106
ANT203 | Enabling AI innovation with Amazon SageMaker Unified Studio
11:30 AM – 12:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Turquoise Theater
BIZ207 | Democratize access to insights with Amazon Quick Suite
8:30 AM – 9:30 AM PST | MGM | Level 1 | Grand 123
ANT204 | Architecting the future: Amazon SageMaker as a data and AI platform
11:00 AM – 12:00 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Pink Theater
ANT317 | Modernize your data warehouse by moving to Amazon Redshift
8:30 AM – 9:30 AM PST | MGM | Level 3 | Chairman’s 366
ANT318 | Scaling Amazon Redshift with a multi-warehouse architecture
11:30 AM – 12:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Pink Theater
ANT216 | What’s new with Amazon SageMaker in the era of unified data and AI
10:00 AM – 11:00 AM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Turquoise Theater
ANT335 | Agentic data engineering with AWS Analytics MCP Servers
BIZ228 | Reimagine business intelligence with Amazon Quick Sight
.
.
.
1:30 PM – 2:30 PM PST | Mandalay Bay | Level 3 South | South Seas E
OPN413 | Transforming Apache Kafka into a Scalable Message Queue
.
.
.
5:30 PM – 6:30 PM PST | Mandalay Bay | Level 3 South | South Seas F
ANT423 | Amazon Kinesis Data Streams under the hood
.
.
.
Chalk talks
These hour-long, highly engaging sessions offer a unique blend of expert insight and collaborative learning. An AWS specialist kicks off with a concise, informative lecture, setting the stage for an in-depth, interactive Q&A. With a limited audience size, you’ll have the opportunity to dive deep into topics, ask pressing questions, and engage in meaningful discussions with both the presenter and fellow attendees.
Monday, Dec 1
Tuesday, Dec 2
Wednesday, Dec 3
Thursday, Dec 4
Friday, Dec 5
8:30 AM – 9:30 AM PST | MGM | Level 1 | Boulevard 167
ANT301-R1 | Accelerating the shift from batch to real-time streaming
11:30 AM – 12:30 PM PST | Caesars Forum | Level 1 | Academy 411
ANT302-R1 | Accelerate GenAI-powered data discovery and sharing with SageMaker Catalog
9:00 AM – 10:00 AM PST | MGM | Level 3 | Room 353
ANT301-R | Accelerating the shift from batch to real-time streaming
ANT316 | Orchestrating with Apache Airflow, MWAA, and SageMaker Unified Studio
Builders’ sessions
Immerse yourself in our builders’ sessions – a hands-on learning experience designed to elevate your AWS skills. These focused, hour-long workshops bring together a small group of up to ten attendees with a dedicated AWS expert at each table.
Monday, Dec 1
Tuesday, Dec 2
Wednesday, Dec 3
Thursday, Dec 4
8:30 AM – 9:30 AM PST | Wynn | Convention Promenade | Latour 7
ANT407-R1 | Building event-driven applications with AWS Streaming and Messaging
OPN407-R | Performance tuning for streaming Ingestion into Apache Iceberg
.
.
.
4:00 PM – 5:00 PM PST | Mandalay Bay | Lower Level North | Islander H
ANT405-R | Build high performance Apache Iceberg data lakes with Amazon S3 Tables
.
.
.
Workshops
Roll your sleeves in our dynamic 2-hour workshops, where you’ll tackle real-world challenges using AWS services. These interactive sessions kick off with a brief, informative lecture to set the stage, then quickly transition into hands-on problem-solving. Bring your laptop and prepare to build alongside AWS experts, who will guide you through practical applications of cloud computing concepts. Whether you’re new to AWS or looking to sharpen your skills, these workshops offer a unique opportunity to learn by doing, enabling you to leave with confidence and applicable knowledge in AWS technologies.
Monday, Dec 1
Tuesday, Dec 2
Wednesday, Dec 3
Thursday, Dec 4
8:00 AM – 10:00 AM PST | Mandalay Bay | Lower Level North | Islander C
ANT402-R1 | Build a fraud detection system with Amazon SageMaker Unified Studio
BIZ204-R | Experience AI-powered BI with Amazon Quick Suite
3:30 PM – 5:30 PM PST | Mandalay Bay | Lower Level North | Islander C
ANT401 | Build an AI-powered enterprise search with Amazon OpenSearch service
.
3:00 PM – 5:00 PM PST | Mandalay Bay | Level 2 South | Mandalay Bay Ballroom K
ANT414 | Scale intelligent analytics with Amazon Redshift multi-cluster architectures
.
.
.
Lightning Talks
Located in the Expo Hall, each of these 20-minute theater presentations are dedicated to a specific customer story, service demo, or AWS Partner offering.
Monday, Dec 1
Tuesday, Dec 2
Wednesday, Dec 3
Thursday, Dec 4
5:00 PM – 5:20 PM PST | Venetian | Level 2 | Hall B | Expo | Theater 4
ANT334 | High-performance NLP & geospatial analysis with Redshift
.
3:00 PM – 3:20 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Lightning Theater
ANT333 | Fast-track to insights: AWS-SAP data strategy
12:30 PM – 12:50 PM PST | Venetian | Level 2 | Hall B | Expo | Theater 3
ANT342 | ITTI’s Cross-Company Data Mesh Blueprint with Amazon SageMaker
6:00 PM – 6:20 PM PST | Venetian | Level 2 | Hall B | Expo | Theater 3
We hope this post acts as your go-to resource for navigating the AWS analytics track at re:Invent 2025. For staying in the know about the most recent trends and advancements in AWS Analytics, follow our LinkedIn page.
Today, I’m happy to announce a new capability to resolve location data for Amazon Sidewalk enabled devices with the AWS IoT Core Device Location service. This feature removes the requirement to install GPS modules in a Sidewalk device and also simplifies the developer experience of resolving location data. Devices powered by small coin cell batteries, such as smart home sensor trackers, use Sidewalk to connect. Supporting built-in GPS modules for products that move around is not only expensive, it can creates challenge in ensuring optimal battery life performance and longevity.
With this launch, Internet of Things (IoT) device manufacturers and solution developers can build asset tracking and location monitoring solutions using Sidewalk-enabled devices by sending Bluetooth Low Energy (BLE), Wi-Fi, or Global Navigation Satellite System (GNSS) information to AWS IoT for location resolution. They can then send the resolved location data to an MQTT topic or AWS IoT rule and route the data to other Amazon Web Services (AWS) services, thus using different capabilities of AWS Cloud through AWS IoT Core. This would simplify their software development and give them more options to choose the optimal location source, thereby improving their product performance.
This launch addresses previous challenges and architecture complexity. You don’t need location sensing on network-based devices when you use the Sidewalk network infrastructure itself to determine device location, which eliminates the need for power-hungry and costly GPS hardware on the device. And, this feature also allows devices to efficiently measure and report location data from GNSS and Wi-Fi, thus extending the product battery life. Therefore, you can build a more compelling solution for asset tracking and location-aware IoT applications with these enhancements.
For those unfamiliar with Amazon Sidewalk and the AWS IoT Core Device Location service, I’ll briefly explain their history and context. If you’re already familiar with them, you can skip to the section on how to get started.
AWS IoT Core integrations with Amazon Sidewalk Amazon Sidewalk is a shared network that helps devices work better through improved connectivity options. It’s designed to support a wide range of customer devices with capabilities ranging from locating pets or valuables, to smart home security and lighting control and remote diagnostics for appliances and tools.
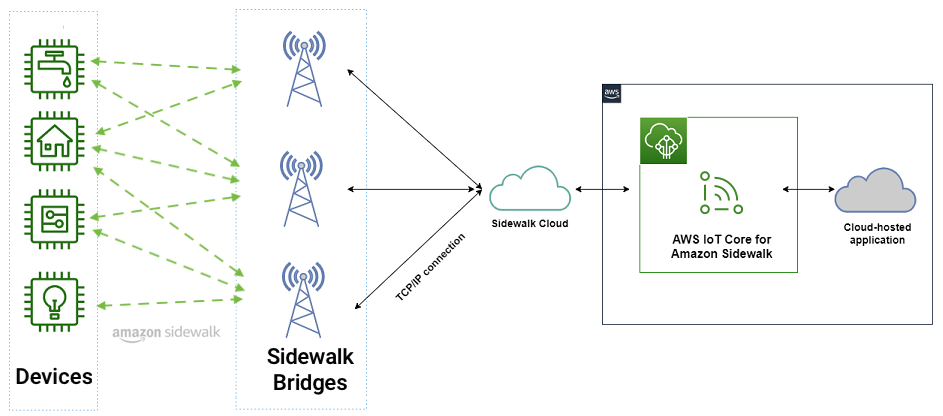
Amazon Sidewalk is a secure community network that uses Amazon Sidewalk Gateways (also called Sidewalk Bridges), such as compatible Amazon Echo and Ring devices, to provide cloud connectivity for IoT endpoint devices. Amazon Sidewalk enables low-bandwidth and long-range connectivity at home and beyond using BLE for short-distance communication and LoRa and frequency-shift keying (FSK) radio protocols at 900MHz frequencies to cover longer distances.
Sidewalk now provides coverage to more than 90% of the US population and supports long-range connected solutions for communities and enterprises. Users with Ring cameras or Alexa devices that act as a Sidewalk Bridge can choose to contribute a small portion of their internet bandwidth, which is pooled to create a shared network that benefits all Sidewalk-enabled devices in a community.
In March 2023, AWS IoT Core deepened its integration with Amazon Sidewalk to seamlessly provision, onboard, and monitor Sidewalk devices with qualified hardware development kits (HDKs), SDKs, and sample applications. As of this writing, AWS IoT Core is the only way for customers to connect the Sidewalk network.
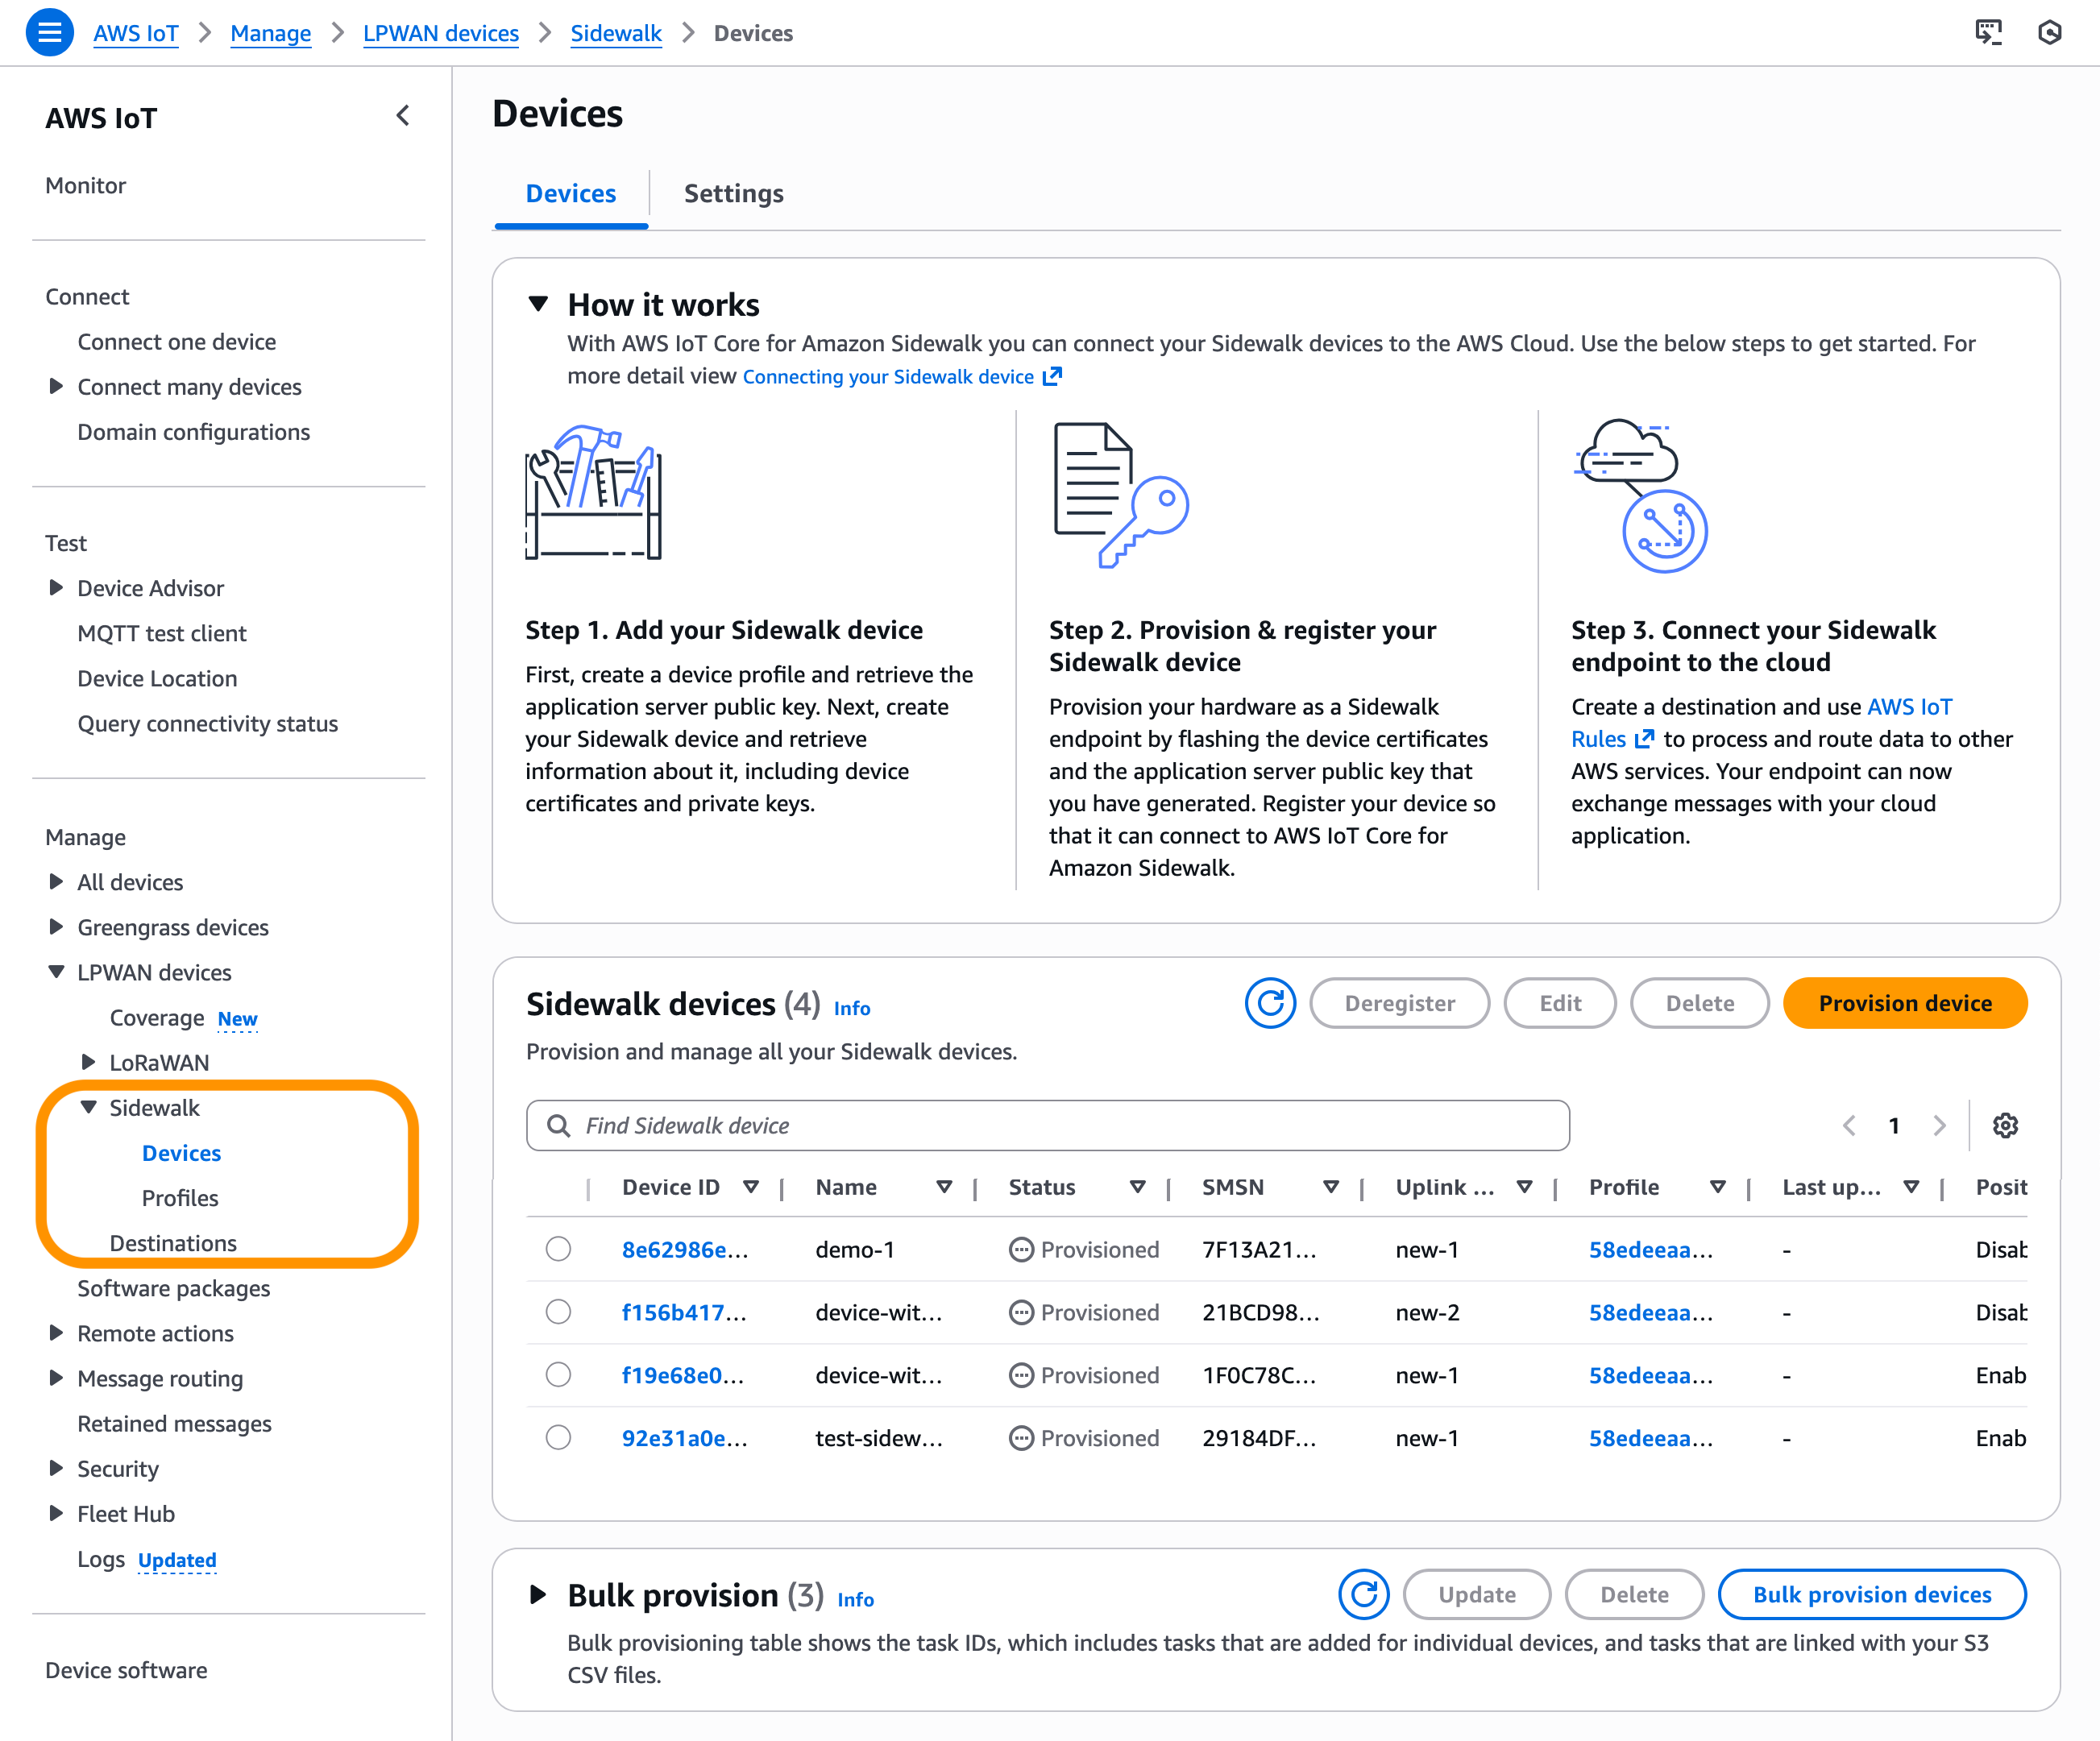
In the AWS IoT Core console, you can add your Sidewalk device, provision and register your devices, and connect your Sidewalk endpoint to the cloud. To learn more about onboarding your Sidewalk devices, visit the Getting started with AWS IoT Core for Amazon Sidewalk in the AWS IoT Wireless Developer Guide.
In November 2022, we announced AWS IoT Core Device Location service, a new feature that you can use to get the geo-coordinates of their IoT devices even when the device doesn’t have a GPS module. You can use the Device Location service as a simple request and response HTTP API, or you can use it with IoT connectivity pathways like MQTT, LoRaWAN, and now with Amazon Sidewalk.
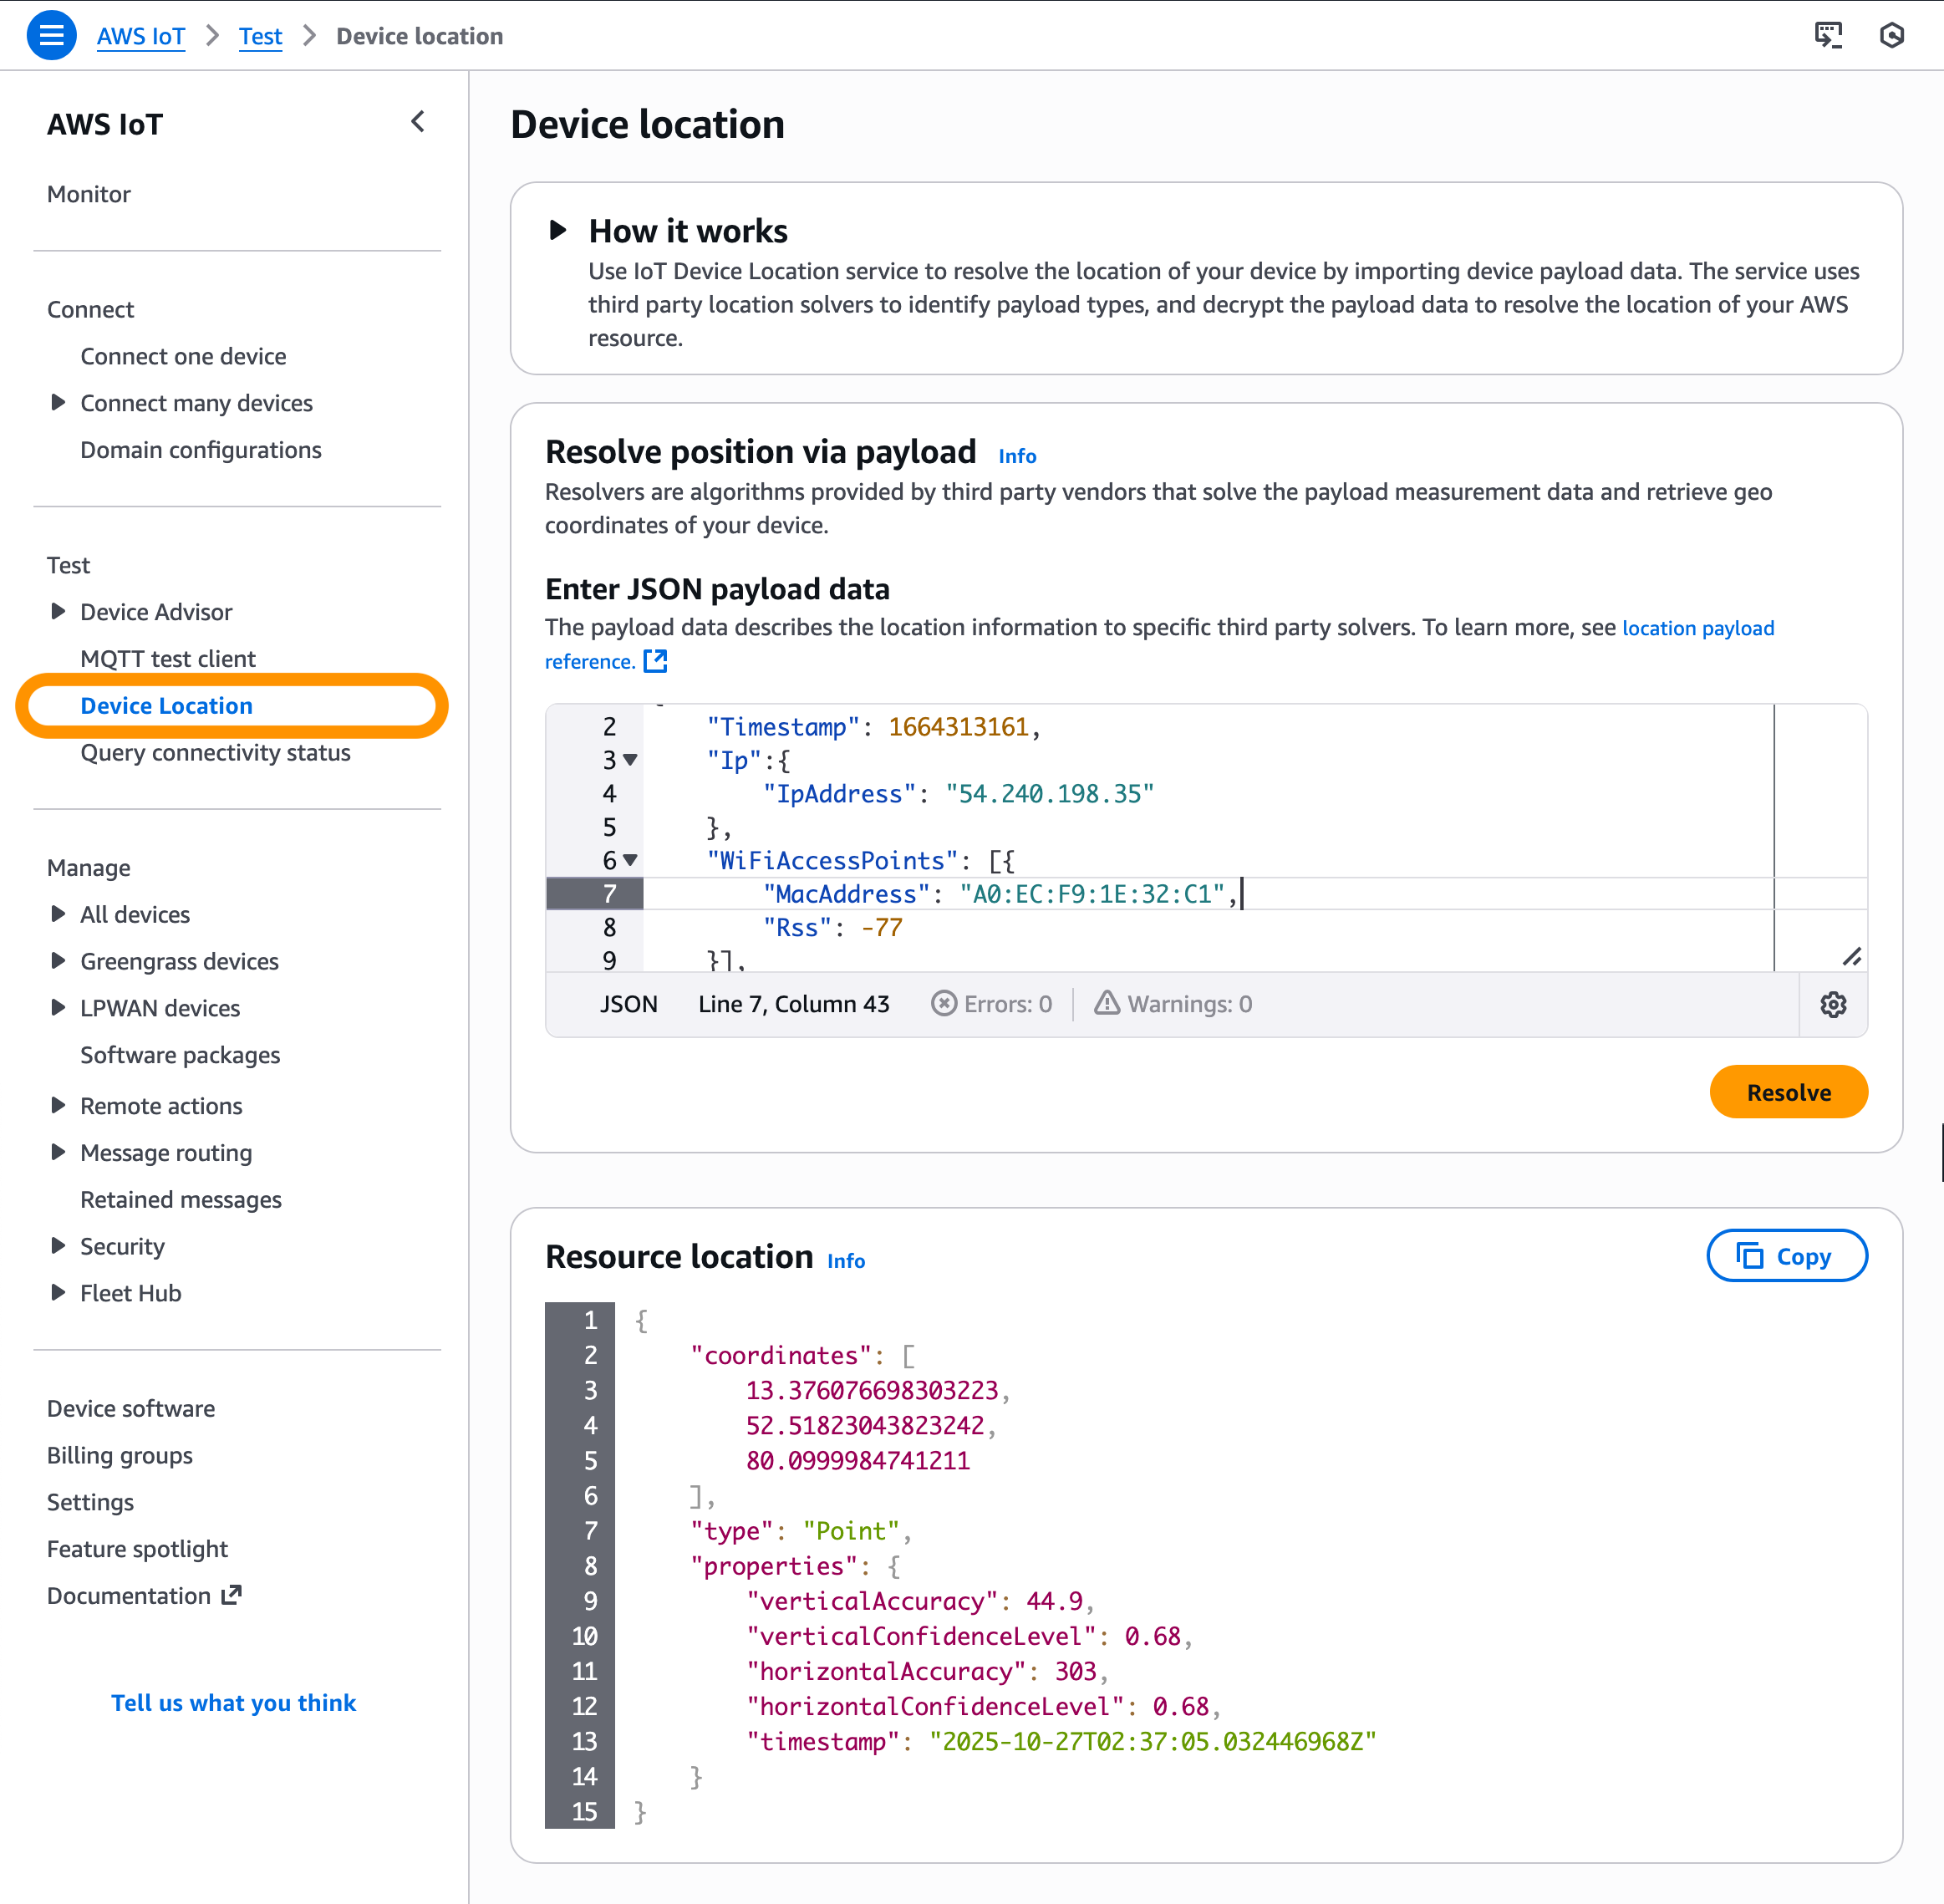
In the AWS IoT Core console, you can test the Device Location service to resolve the location of your device by importing device payload data. Resource location is reported as a GeoJSON payload. To learn more, visit the AWS IoT Core Device Location in the AWS IoT Core Developer Guide.
Customers across multiple industries like automotive, supply chain, and industrial tools have requested a simplified solution such as the Device Location service to extract location-data from Sidewalk products. This would streamline customer software development and give them more options to choose the optimal location source, thereby improving their product.
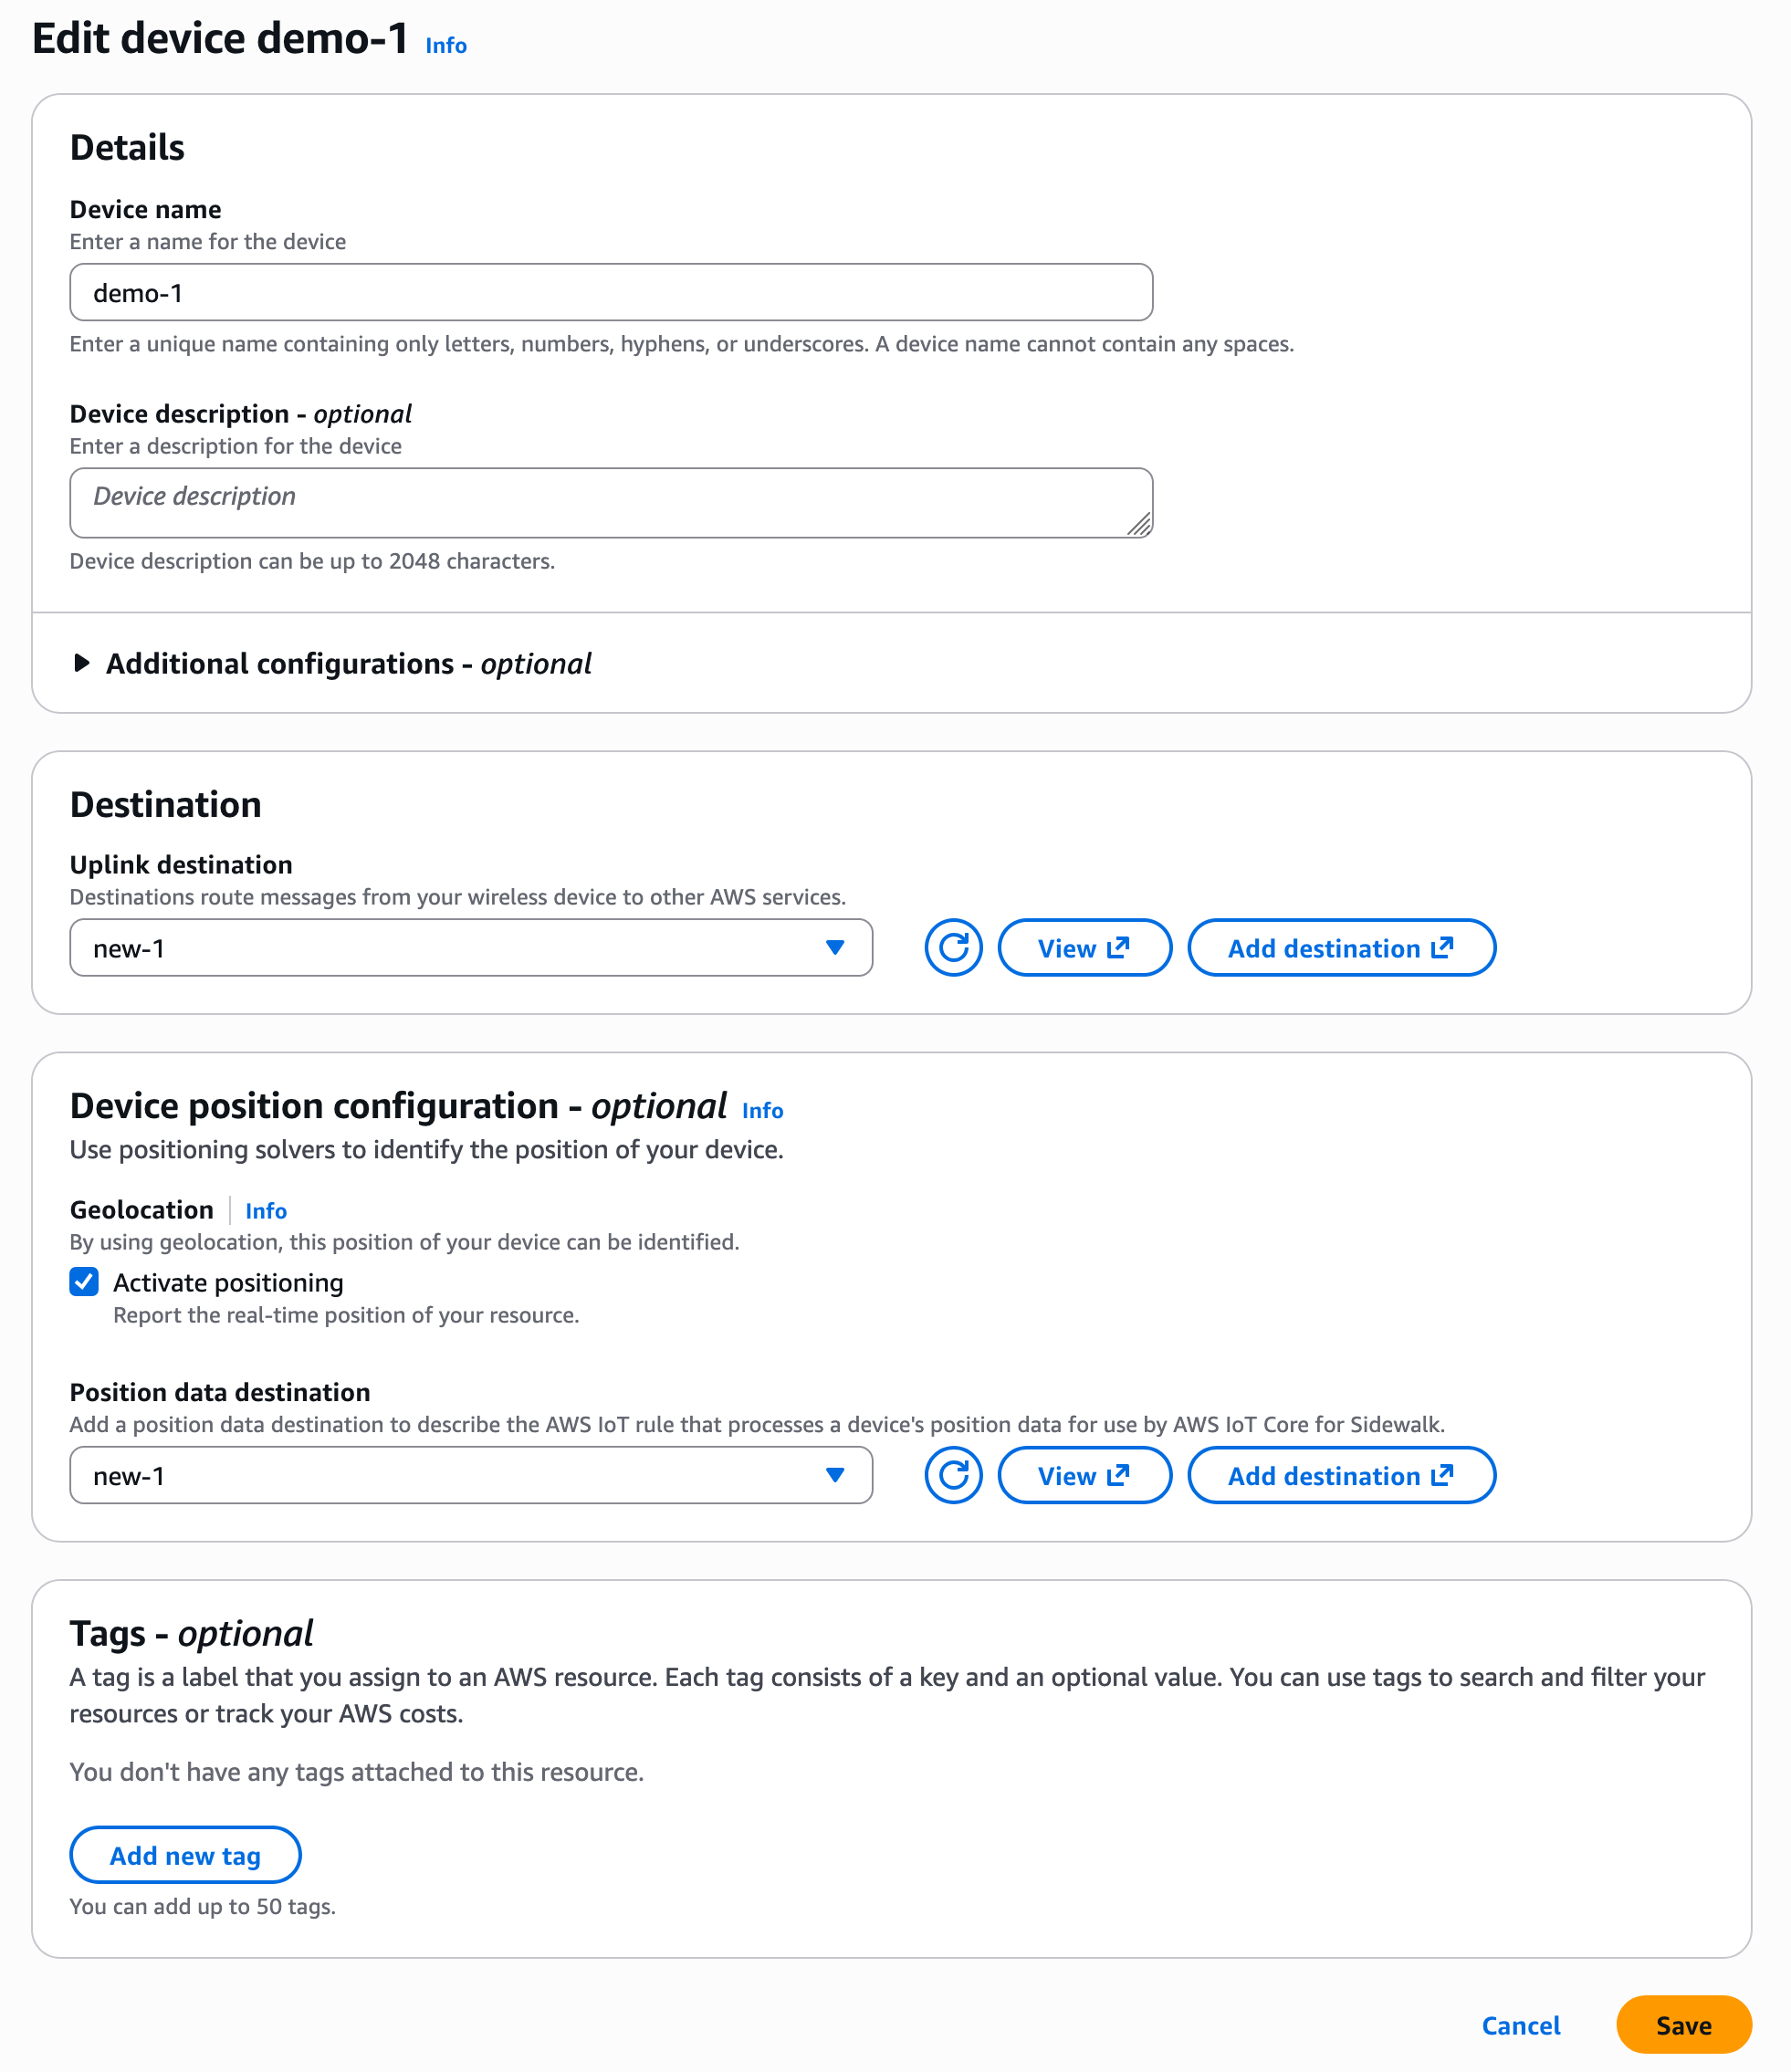
Get started with a Device Location integration with Amazon Sidewalk To enable Device Location for Sidewalk devices, go to the AWS IoT Core for Amazon Sidewalk section under LPWAN devices in the AWS IoT Core console. Choose Provision device or your existing device to edit the setting and select Activate positioning in the Geolocation option when creating and updating your Sidewalk devices.
While activating position, you need to specify a destination where you want to send your location data. The destination can either be an AWS IoT rule or an MQTT topic.
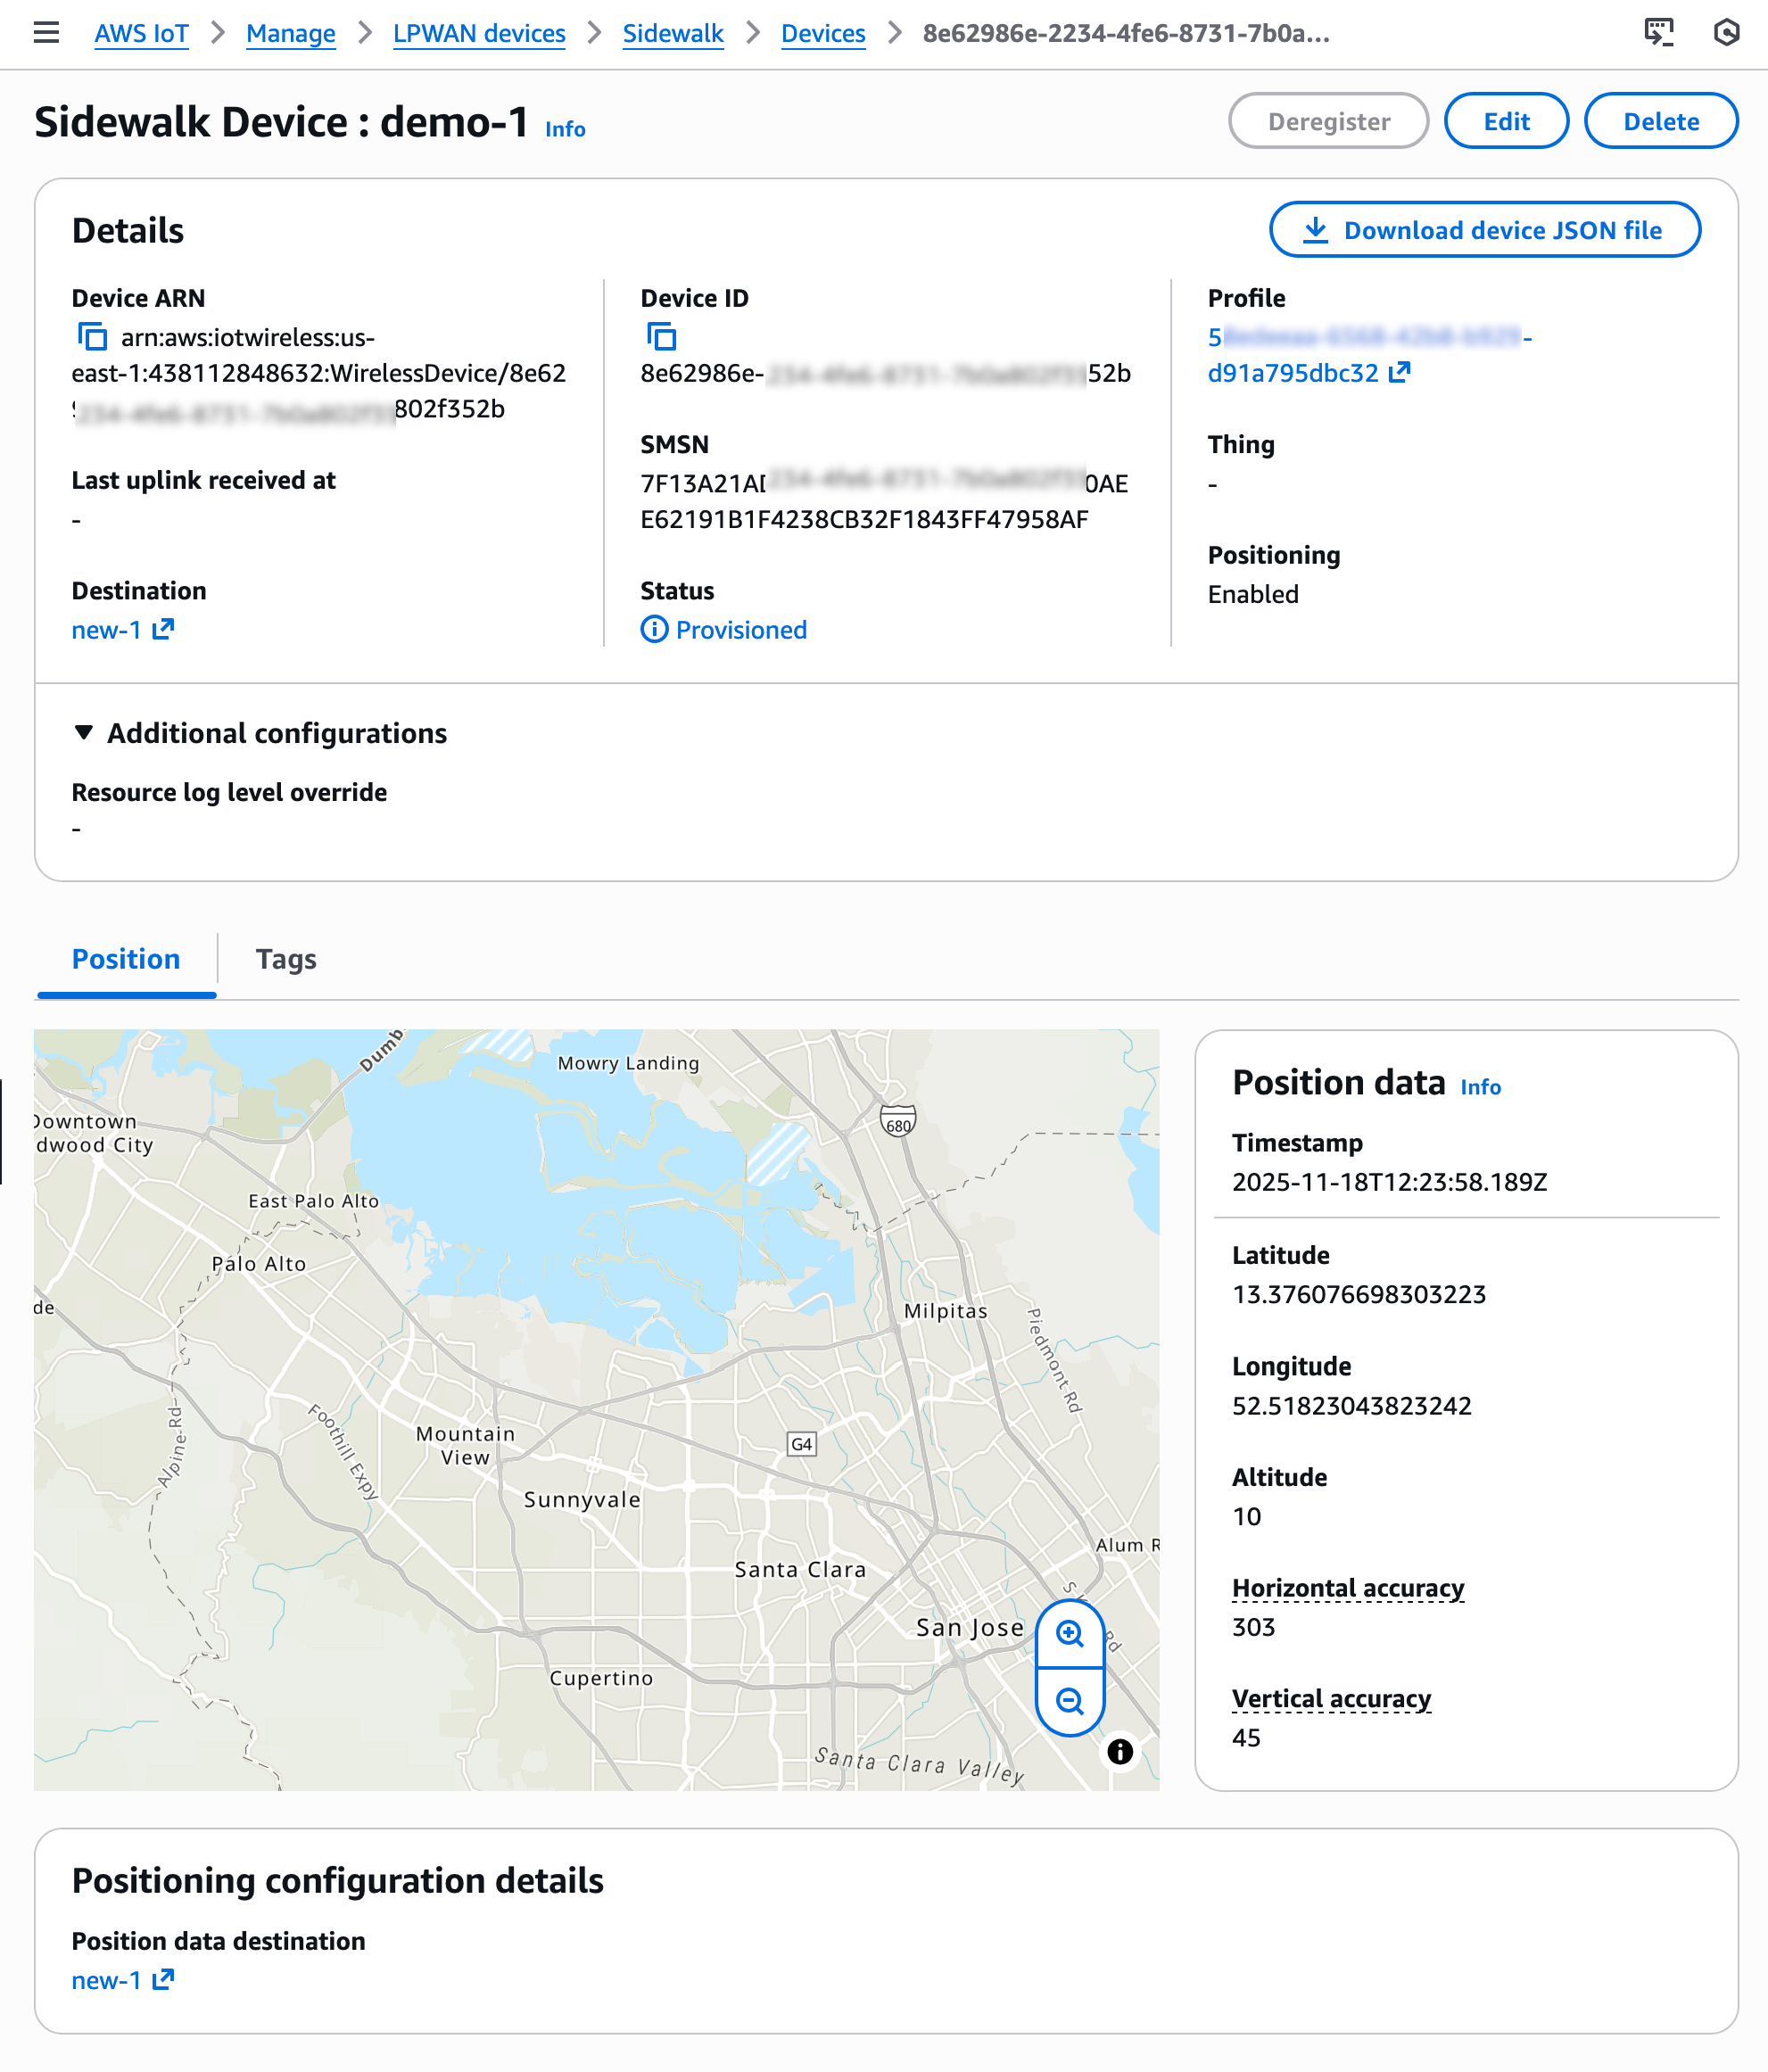
After your Sidewalk device establishes a connection to the Amazon Sidewalk network, the device SDK will send the GNSS-, Wi-Fi- or BLE-based information to AWS IoT Core for Amazon Sidewalk. If the customer has enabled Positioning, then AWS IoT Core Device Location will resolve the location data and send the location data to the specified Destination. After your Sidewalk device transmits location measurement data, the resolved geographic coordinates and a map pin will also be displayed in the Position section for the selected device.
You will also get location information delivered to your destination in GeoJSON format, as shown in the following example:
Now available AWS IoT Core Device Location integration with Amazon Sidewalk is now generally available in the US East (N. Virginia) Region. To learn more about use cases, documentation, sample codes, and partner devices, visit the AWS IoT Core for Amazon Sidewalk product page.
The SUSE Security Team has published an in-depth
article on its findings after reviewing a D-Bus service contained
in LightDM
Greeter by KDE (the lightdm-kde-greeter package)
for addition to openSUSE Tumbleweed. The team found a privilege
escalation from the lightdm service user to root, as
well as other attack vectors in the service:
In agreement with upstream, we assigned CVE-2025-62876 to track the lightdm service user to root privilege escalation aspect described in
this report. The severity of the issue is low, since it only affects
defense-in-depth (if the lightdm service user were compromised) and
the problematic logic can only be reached and exploited if triggered
interactively by a privileged user.
The fixes are contained in the 6.0.4
release of the project.
Version
145 of the Thunderbird email client has been released. Notable
changes in this release include enabling DNS over HTTPS, support for
Microsoft Exchange via Exchange Web Services, and quite a few bug
fixes. As of 145, the project is no longer shipping 32-bit binaries
for Linux on x86.
This is a guest post by Umesh Dangat, Senior Principal Engineer for Distributed Services and Systems at Yelp, and Toby Cole, Principle Engineer for Data Processing at Yelp, in partnership with AWS.
Yelp processes massive amounts of user data daily—over 300 million business reviews, 100,000 photo uploads, and countless check-ins. Maintaining sub-minute data freshness with this volume presented a significant challenge for our Data Processing team. Our homegrown data pipeline, built in 2015 using then-modern streaming technologies, scaled effectively for many years. As our business and data needs evolved, we began to encounter new challenges in managing observability and governance across an increasingly complex data ecosystem, prompting the need for a more modern approach. This affected our outage incidents, making it harder to both assess impact and restore service. At the same time, our streaming framework struggled with Kafka for data streaming and permanent data storage. In addition, our connectors to analytical data stores experienced latencies exceeding 18 hours.
This came to a head when our efforts to comply with General Data Protection Regulation (GDPR) requirements revealed gaps in our infrastructure that would require us to clean up our data, while simultaneously maintaining operational reliability and reducing data processing times. Something had to change.
In this post, we share how we modernized our data infrastructure by embracing a streaming lakehouse architecture, achieving real-time processing capabilities at a fraction of the cost while reducing operational complexity. With this modernization effort, we reduced analytics data latencies from 18 hours to mere minutes, while also removing the need for using Kafka as a permanent storage for our change log streams.
The problem: Why we needed change
We started this transformation by initiating a migration from self-managed Apache Kafka to Amazon Managed Streaming for Apache Kafka (Amazon MSK), which significantly reduced our operational overhead and enhanced security. Amazon MSK’s express brokers also provided better elasticity for our Apache Kafka clusters. While these improvements were a promising start, we recognized the need for a more fundamental architectural change
Legacy architecture pain points
Let’s examine the specific challenges and limitations of our previous architecture that prompted us to seek a modern solution.
The following diagram depicts Yelp’s original data architecture.
Kafka topics proliferated across our infrastructure, creating long processing chains. As a result, each hop added latency, operational overhead, and storage costs. The system’s reliance on Kafka for both ingestion and storage created a fundamental bottleneck—Kafka’s architecture, optimized for high-throughput messaging, wasn’t designed for long-term storage and to handle complex querying patterns.
Another challenge was our custom “Yelp CDC” format—a proprietary change data capture language—was powerful and tailored to our needs. However, as our team grew and our use cases expanded, it introduced complexity and a steeper learning curve for new engineers. It also made integrations with off-the-shelf systems more complex and maintenance intensive.
The cost and latency trade-off
The traditional trade-off between real-time processing and cost efficiency had us caught in an expensive bind. Real-time streaming systems demand significant resources to maintain state within compute engines like Apache Flink, keep multiple copies of data across Kafka clusters, and run always-on processing jobs. Our infrastructure costs were growing, and it was largely driven by:
Long Kafka chains: Data often traversed 4-5 Kafka topics before reaching its destination and each topic was replicated for reliability
Duplicate data storage: The same data existed in multiple formats across different systems—raw in Kafka, processed in intermediate topics, and final forms in data warehouses and Flink RocksDB for join-like use cases
Complex custom tooling maintenance: The proprietary nature of our tools meant engineering resources were focused on maintenance rather than building new capabilities
Meanwhile, our business requirements became more demanding. Teams at Yelp needed faster insights, near-real-time results, and the ability to quickly run complex historical analyses without delay. This pushed us to shape our new architecture to improve streaming discovery and metadata visibility, provide more flexible transformation tooling, and simplify operational workflows with faster recovery times.
Understanding the streamhouse concept
To understand how we solved our data infrastructure challenges, it’s important to first grasp the concept of a streamhouse and how it differs from traditional architectures.
Evolution of data architecture
To understand why a streaming lakehouse or streamhouse was the answer to our challenges, it’s helpful to trace the evolution of data architectures. The journey from data warehouses to modern streaming systems reveals why each generation solved certain problems while creating new ones.
Data warehouses like Amazon Redshift and Snowflake brought structure and reliability to analytics, but their batch-oriented nature meant accepting hours or days of latency. Data lakes emerged to handle the volume and variety of big data, using low-cost object storage like Amazon S3, but often became “data swamps” without proper governance. The lakehouse architecture, pioneered by technologies like Apache Iceberg and Delta Lake, promised to combine the best of both, the structure of warehouses with the flexibility and economics of lakes.
But even lakehouses were designed with batch processing in mind. While they added streaming capabilities, these were often bolted on rather than fundamental to the architecture. What we needed was something different: a reimagining that treated streaming as a first-class citizen while maintaining lakehouse economics.
What makes a streamhouse different
A streamhouse, as we define it, is “a stream processing framework with a storage layer that leverages a table format, making intermediate streaming data directly queryable.” This seemingly simple definition represents a fundamental shift in how we think about data processing.
Traditional streaming systems maintain dynamic tables like materialized views in databases, but these aren’t directly queryable. You can only consume them as streams, limiting their utility for ad-hoc analysis or debugging. Lakehouses, conversely, excel at queries but struggle with low-latency updates and complex streaming operations like out-of-order event handling or partial updates.
The streamhouse bridges this gap by:
Treating batch as a special case of streaming, rather than a separate paradigm
Making data, including intermediate processing results, queryable via SQL
Providing streaming-native features like database change-data capture (CDC) and temporal joins
Leveraging cost-effective object storage while maintaining minute-level latencies
Core capabilities we needed
Our requirements for a streaming lakehouse were shaped by years of operating at scale:
Real-time processing with minute-level latency: While sub-second latency wasn’t necessary for most use cases, our previous hours-long delays weren’t acceptable. The sweet spot was processing latencies measured in minutes fast enough for real-time decision-making but relaxed enough to leverage cost-effective storage.
Efficient CDC handling: With numerous MySQL databases powering our applications, the ability to efficiently capture and process database changes was crucial. The solution needed to handle both initial snapshots and ongoing changes seamlessly, without manual intervention or downtime.
Cost-effective scaling: The architecture had to break the linear relationship between data volume and cost. This meant leveraging tiered storage, with hot data on fast storage and cold data on low-cost object storage, all while maintaining query performance.
Built-in data management: Schema evolution, data lineage, time travel queries, and data quality controls needed to be first-class features, not afterthoughts. Our experience maintaining our custom Schematizer taught us that these capabilities were essential for operating at scale.
The solution architecture
Our modernized data infrastructure combines several key technologies into a cohesive streamhouse architecture that addresses our core requirements while maintaining operational efficiency.
Our technology stack selection
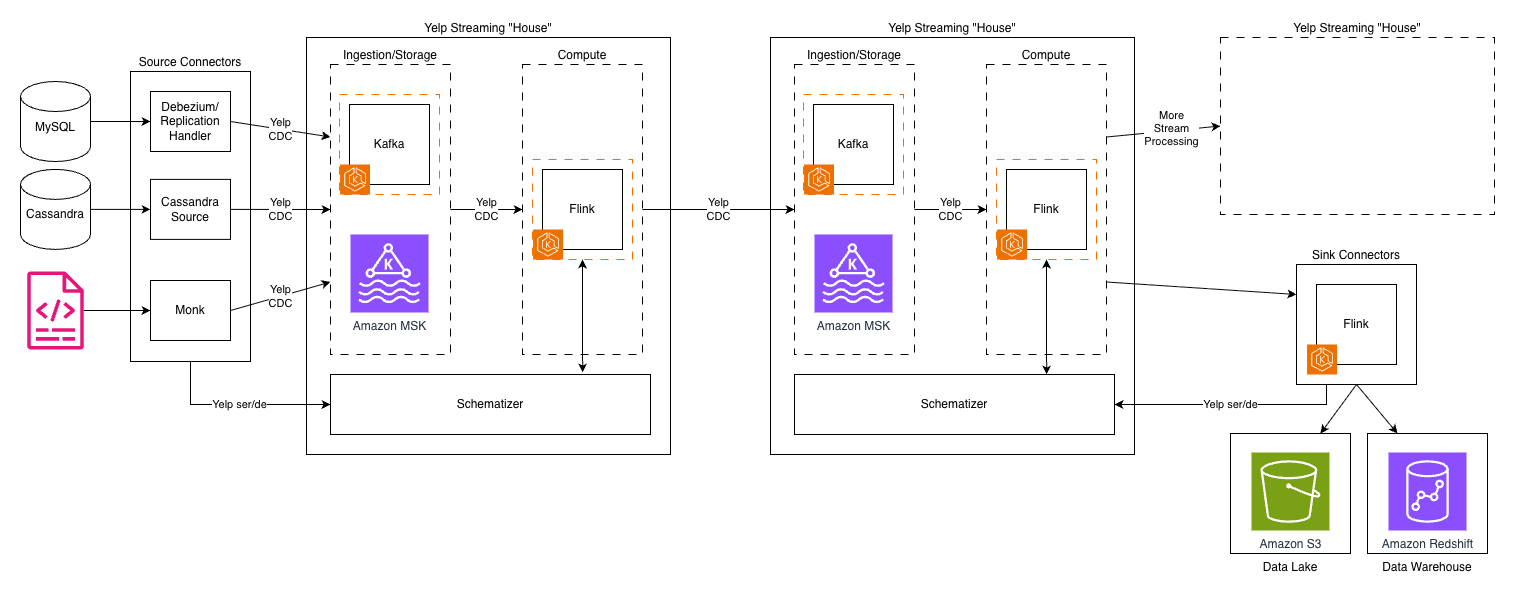
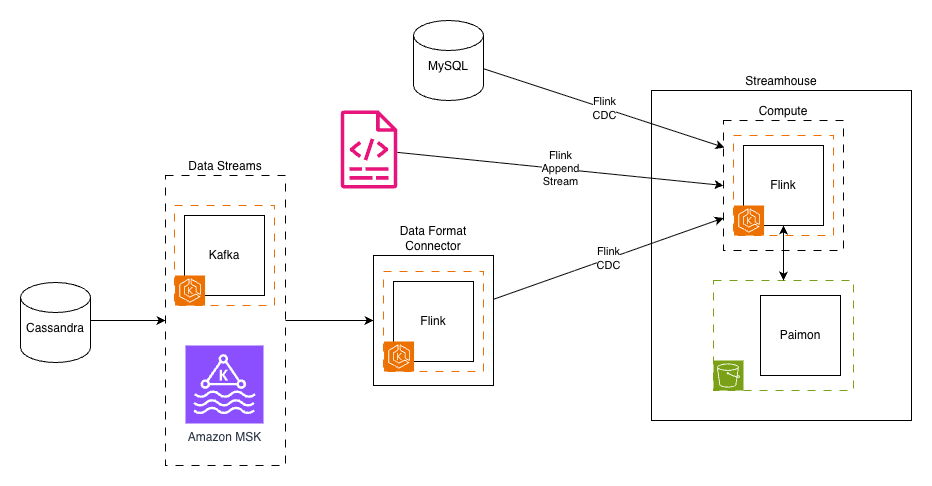
We carefully selected and integrated several proven technologies to build our streamhouse solution.The following diagram depicts Yelp’s new data architecture.
After extensive evaluation, we assembled a modern streaming lakehouse stack, streamhouse, built on proven open source technologies:
Amazon MSK continues to deliver existing streams as they did before from source applications and services.
Apache Flink on Amazon EKS served as our compute engine, a natural choice given our existing expertise and investment in Flink-based processing. Its powerful stream processing capabilities, exactly-once semantics, and mature framework made it ideal for the computational layer.
Apache Paimon emerged as the key innovation, providing the streaming lakehouse storage layer. Born from the Flink community’s FLIP-188 proposal for built-in dynamic table storage, Paimon was designed from the ground up for streaming workloads. Its LSM-tree-based architecture provided the high-speed ingestion capabilities we needed.
Amazon S3 serves as our streamhouse storage layer, offering highly scalable capacity at a fraction of the cost. The shift from compute-coupled storage (Kafka brokers) to object storage represented a fundamental architectural change that unlocked massive cost savings.
Flink CDC connectors replaced our custom CDC implementations, providing battle-tested integrations with databases like MySQL. These connectors handled the complexity of initial snapshots, incremental updates, and schema changes automatically.
Architectural transformation
The transformation from our legacy architecture to the streamhouse model involved three key architectural shifts:
1. Decoupling ingestion from storage
In our old world, Kafka handled both data ingestion and storage, creating an expensive coupling. Every byte ingested had to be stored on Kafka brokers with replication for reliability. Our new architecture separated these concerns: Flink CDC handled ingestion by immediately writing to Paimon tables backed by S3. This separation reduced our storage costs by over 80% and improved reliability through the 11 nines of durability of S3.
2. Unified data format
The migration from our proprietary CDC format to the industry-standard Debezium format was more than a technical change. It reflected a broader move toward community-supported standards. We built a Data Format Converter that bridged the gap, allowing legacy streams to continue functioning while new streams leveraged standard formats. This approach facilitated backward compatibility while paving the way for future simplification.
3. Streamhouse tables
Perhaps the most radical change was replacing some of our Kafka topics with Paimon tables. These weren’t just storage locations—they were dynamic, versioned, queryable entities that supported:
Time travel queries in the table’s snapshot retention period
Automatic schema evolution without downtime
SQL-based access for both streaming and batch workloads
Built-in compaction and optimization
Key design decisions
Several key design decisions shaped our implementation:
SQL as the primary interface: Rather than requiring developers to write Java or Scala code for every transformation, SQL became our lingua franca. This democratized access to streaming data, allowing analysts and data scientists to work with real-time data using familiar tools.
Separation of compute and storage: By decoupling these layers, we could scale them independently. A spike in processing needs no longer meant provisioning more storage, and historical data could be kept indefinitely without impacting compute costs.
Embracing open source standards: The shift from home-grown formats and tools to community-supported projects reduced our maintenance burden and accelerated feature development. When issues arose, our engineers could leverage community knowledge rather than debugging in isolation.
Implementation journey
Our transition to the new streamhouse architecture followed a carefully planned path, encompassing prototype development, phased migration, and systematic validation of each component.
Migration strategy
Our migration to the streamhouse architecture required careful planning and execution. The strategy had to balance the need for transformation with the reality of maintaining critical production systems.
1. Prototype development
Our journey began with building foundational components:
Pure Java client library: Removing Scala dependencies were crucial for broader adoption. Our new library removed reliance on Yelp-specific configurations, allowing it to run in many environments.
Data Format Converter: This bridge component translated between our proprietary CDC format and the standard Debezium format, making sure existing consumers could continue operating during the migration.
Paimon ingestor: A Flink job that could ingest data from Kafka sources into Paimon tables, handling schema evolution automatically.
2. Phased rollout approach
Rather than attempting a “big bang” migration, we adopted a per-use case approach—moving a vertical slice of data rather than the entire system at once. Our phased rollout followed these steps:
Select a representative, real-world use case that provides broad coverage of the existing feature set.
In our use case, this included data sourced from both databases and event streams, with writes going to Cassandra and Nrtsearch
Re-implement the use case on the new stack in a development environment using sample data to test the logic
Shadow-launch the new stack in production to test it at scale
This was a critical step for us, as we had to iterate through various configuration tweaks before the system could reliably sustain our production traffic.
Verify the new production deployment against the legacy system’s output
Switch live traffic to the new system only after both the Yelp Platform team and data owners are confident in its performance and reliability
Decommission the legacy system for that use case once the migration is complete
This phased approach allowed our team to build confidence, identify issues early, and refine our processes before touching business-critical systems in production.
Technical challenges we overcame
The migration surfaced several technical challenges that required innovative solutions:
System integration: We developed comprehensive monitoring to track end-to-end latencies and built automated alerting to detect any degradation in performance.
Performance tuning: Initial write performance to Paimon tables was suboptimal for our higher-throughput streams. After careful analysis, we identified that Paimon was re-reading manifest files from S3 on every commit. To alleviate this, we enabled Paimon’s sink writer coordinator cache setting, which is disabled by default. This massively reduced the number of S3 calls during commits. We also found that writing parallelism in Paimon is limited by the number of “buckets” within a partition. Selecting the right number of buckets to allow you to scale horizontally, but also not spread your data too thinly is important for balancing write performance against query performance.
Data validation: Validating data consistency between our legacy Yelp CDC streams and the new Debezium-based format presented notable challenges. During the parallel run phase, we implemented comprehensive validation frameworks to make sure the Data Format Convertor accurately transformed messages, while maintaining data integrity, ordering guarantees, and schema compatibility across both systems.
Data migration complexity: For consistency, we developed custom tooling to verify ordering guarantees and implemented parallel running of old and new systems. We chose Spark as the framework to implement our validations as every data source and sink in our framework has mature connectors, and Spark is a well-supported system at Yelp.
Simplified streaming stack: By replacing multiple custom components with standardized tools, we avoided years of technical debt in one migration. We reduced our complexity and thereby simplified our entire streaming architecture, leading to higher reliability and less maintenance overhead. Our Schematizer, encryption layer, and custom CDC format were all replaced by built-in features from Paimon and standard Kafka, along with IAM controls across S3 and MSK.
Fine-grained access management: Moving our analytical use cases read via Iceberg unlocked a huge win for us: the ability to enable AWS Lake Formation on our data lake. Previously, our access management relied on large, complex S3 bucket policy documents that were approaching their size limits. By moving to Lake Formation we could build an access request lifecycle into our in-house Access Hub to automate access granting and revocation.
Built-in data management features: Capabilities that would have required months of custom development came out-of-the-box, such as automatic schema evolution, time travel queries, and incremental snapshots for efficient processing.
Potential for reduced operational costs: We anticipate that transitioning from Kafka storage to S3 in a streamhouse architecture will significantly reduce storage costs. Avoiding long Kafka chains will also simplify data pipelines and reduce compute costs.
Enhanced troubleshooting capabilities: The streamhouse architecture promises built-in observability features that will make debugging easier. Rather than having to manually look through event streams for problematic data, which can be time-consuming and complex for multi-stream pipelines, engineers can now query live data directly from tables using standard SQL.
Lessons learned and best practices
Throughout this transformation, we gained valuable insights about both technical implementation and organizational change management that can benefit others undertaking similar modernization efforts.
Technical insights
Our journey revealed several crucial technical lessons:
Battle-tested open source wins: Choosing Apache Paimon and Flink CDC over custom solutions proved wise. The community support, continuous improvements, and shared knowledge base accelerated our development and reduced risk.
SQL interfaces democratize access: Making streaming data accessible via SQL transformed who could work with real-time data. Engineers and analysts familiar with SQL can now understand how streaming pipelines work. The barrier to entry has been significantly lowered as engineers no longer need to understand Flink-specific APIs to create a streaming application.
Separation of storage and compute is fundamental: This architectural principle unlocked cost savings and operational flexibility that wouldn’t have been possible otherwise. Our teams can now optimize storage and compute independently based on their specific needs.
Organizational learnings
The human side of the transformation was equally important:
Phased migration reduces risk: Our gradual approach allowed teams to build confidence and expertise, while maintaining business continuity. Each successful phase created momentum for the next. Building trust with newer systems helps gain velocity in later stages of migrations.
Backward compatibility enables progress: By maintaining compatibility layers, our teams could migrate at their own pace without forcing synchronized changes across the organization.
Investment in learning pays dividends: Giving our teams space to learn new technologies like Paimon and streaming SQL had some opportunity cost, but they paid off through increased productivity and reduced operational burden.
Conclusion
Our transformation to a streaming lakehouse architecture (streamhouse) has revolutionized Yelp’s data infrastructure, delivering impressive results across multiple dimensions. By implementing Apache Paimon with AWS services like Amazon S3 and Amazon MSK, we reduced our analytics data latencies from 18 hours to just minutes while cutting storage costs by 80%. The migration also simplified our architecture by replacing multiple custom components with standardized tools, significantly reducing maintenance overhead and improving reliability.
Key achievements include the successful implementation of real-time processing capabilities, streamlined CDC handling, and enhanced data management features like automatic schema evolution and time travel queries. The shift to SQL-based interfaces has democratized access to streaming data, while the separation of compute and storage has given us unprecedented flexibility in resource optimization. These improvements have transformed not just our technology stack, but also how our teams work with data.
For organizations facing similar challenges with data processing latency, operational costs, and infrastructure complexity, we encourage you to explore the streamhouse approach. Start by evaluating your current architecture against modern streaming solutions, particularly those leveraging cloud services and open-source technologies like Apache Paimon. Make sure to leverage security best practices when implementing your solution. You can find AWS security best practices here. Visit the Apache Paimon website or AWS documentation to learn more about implementing these solutions in your environment.
We’re proud to share that Rapid7 has been recognized as a Leader in the 2025 Gartner® Magic Quadrant™ for Exposure Assessment Platforms (EAP). We believe this recognition underscores our commitment to redefining security operations by embedding continuous, business-aligned exposure management into the core of modern defense strategies.
Our approach: Exposure Command at the core
At the root of Rapid7’s leadership is Exposure Command, our unified exposure management solution, underpinned by complete attack surface visibility, threat-informed risk assessment and integrated automated remediation capabilities.
Key capabilities highlighted in the report include:
Unified visibility across environments: Broad attack surface visibility with native support across hybrid infrastructure including on-prem, cloud, containers, and IoT/OT, alongside extensive integrations with third-party security and ITOps tools.
Threat-validated prioritization: Prioritization enhanced with real-world exploit intelligence, plus continuous red teaming and ad-hoc penetration testing through comprehensive managed services.
Comprehensive, AI-driven remediation: Prebuilt workflows and playbooks, intelligent automation, and dynamic persona-centric reporting.
Why exposure assessment matters more than ever
The security landscape has fundamentally changed. Traditional vulnerability management largely centered around point-in-time scans and CVSS scores can no longer keep pace with the dynamic, hybrid environments that define today’s enterprise. Organizations face an ever-expanding attack surface across cloud, on-prem, SaaS, and OT environments while regulations continue to evolve.
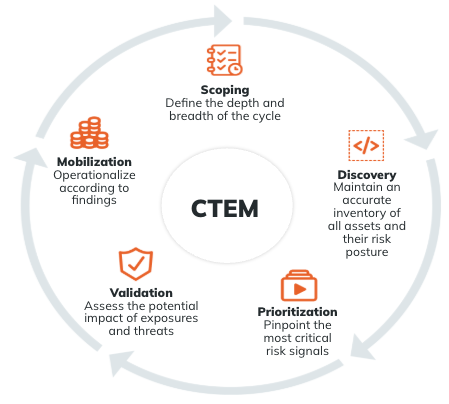
This means a dramatic expansion in the scope of IT and security leaders from tech-centric systems management and patching to a core pillar of the business at large. As a result, exposure management is no longer about finding more; it’s about finding what matters and acting on it decisively. This aligns directly with Gartner’s CTEM model, which calls for a continuous, outcome-focused cycle of scoping, prioritization, validation, and mobilization.
Why CTEM + EAP are the future of risk reduction
CTEM isn’t just a buzzword and a new acronym, it’s the next evolution of proactive security, acknowledging a core truth: no organization can patch everything, nor should they try.
The goal is validated exposure reduction through five stages:
Business-aligned scoping (e.g., revenue-generating services, critical data systems)
Threat-informed prioritization with real-world intelligence
Validation via attack-path modeling or adversary emulation (e.g., PTaaS, BAS, AEV)
Mobilization through integrated, repeatable remediation workflows
Gartner suggests CTEM is a way to translate technical vulnerabilities into business-relevant risks and mobilize cross-functional teams in response. EAPs, which Gartner defines as platforms that continuously identify and prioritize exposures across all environments with business and threat context, provide the operational foundation for CTEM.
⠀
⠀
Rapid7’s EAP capabilities allow teams to operationalize CTEM by translating technical findings into business-relevant risk and enabling cross-functional response, bridging the gap between posture and business continuity.
Looking ahead
As exposure management evolves from a siloed security function to an operational imperative, Rapid7 will continue to lead with innovation, transparency, and a relentless focus on customer outcomes. We believe our position as a Leader in the 2025 Gartner® Magic Quadrant™ for Exposure Assessment Platforms is not just a recognition of the work we’ve done but a signal to the market of what’s next. Click here to download the full Report.
The European Astro Pi Challenge is a collaboration between ESA, the national European Space Education Resource Offices, and the Raspberry Pi Foundation. The 2025/26 challenge, which is currently open for registration, marks 10 years of incredible opportunities for young people to send their code into space.
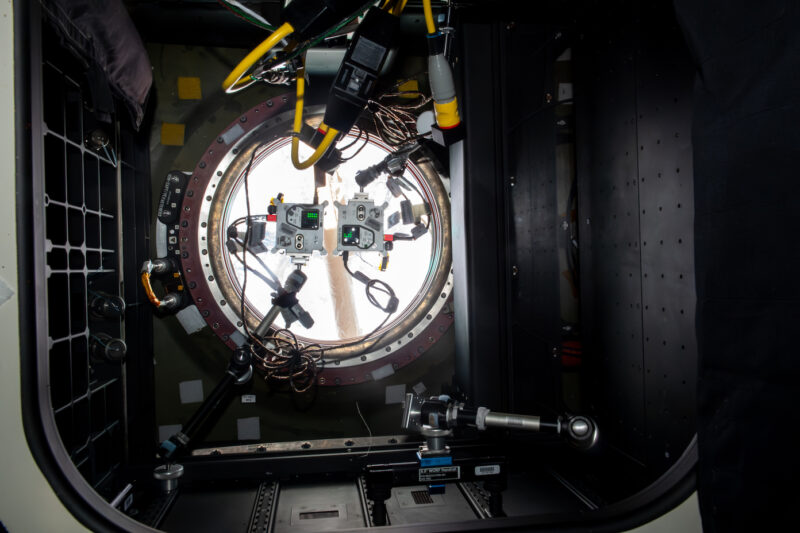
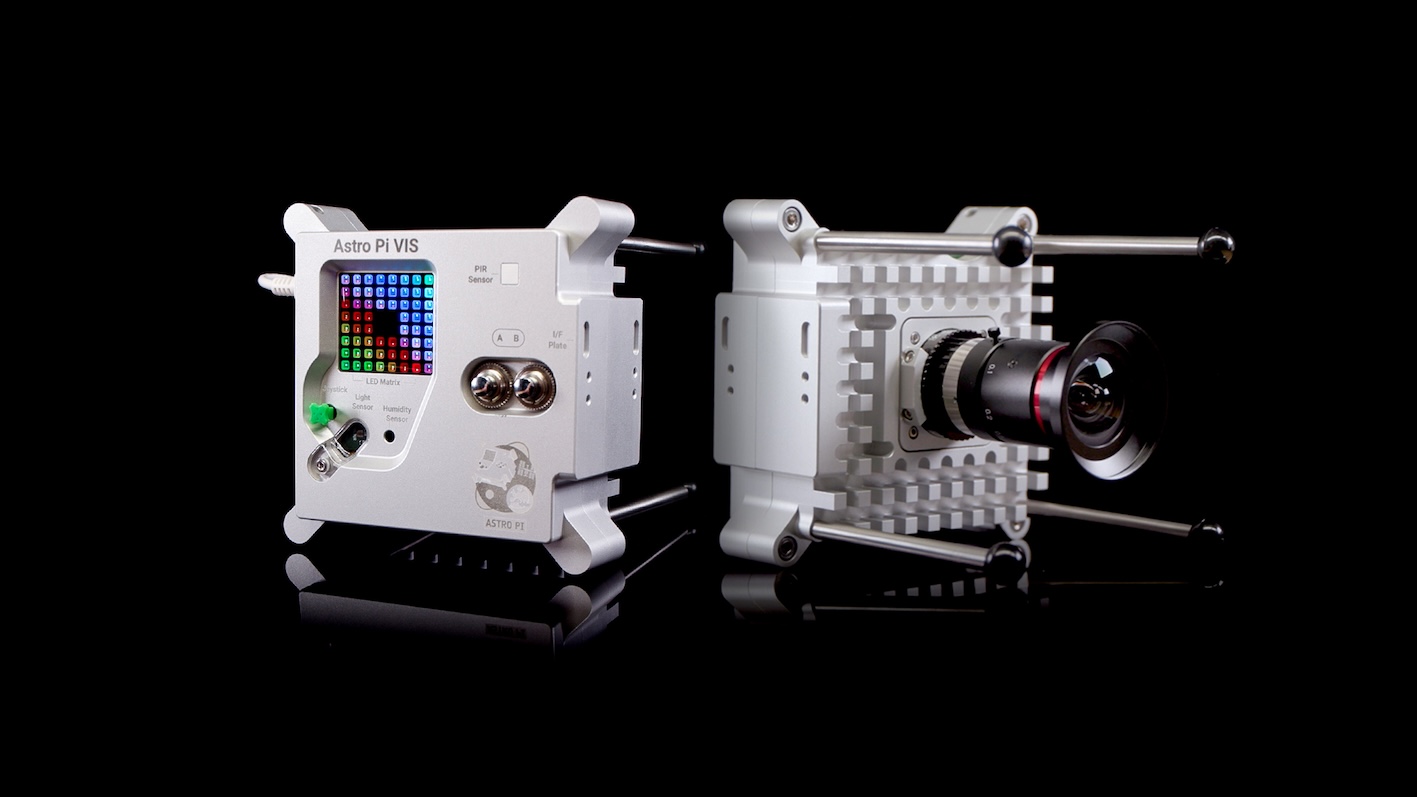
The Astro Pi computers inside the International Space Station, where young people’s programs run.
In this blog post, we are pleased to share the Astro Pi 2024/25 impact report, where we look at ways in which the Astro Pi Challenge is bringing value to the lives of many young people and mentors, based on survey responses and interviews. Along the way, we’ll debunk some myths about space science.
How Astro Pi makes space science accessible
Here at the Raspberry Pi Foundation, we’ve heard a few myths about space science and coding, and how daunting it can be to write a computer program, let alone one that can run in space. We can’t let these myths stand — instead we’re going to debunk them, equipped with evidence we’ve collected about the 2024/25 Astro Pi Challenge and previous challenge rounds.
Read on for some astronomical facts from our latest impact report, and get ready to help young people in your community send their code into space.
Myth 1: You have to be a rocket scientist to send things into space
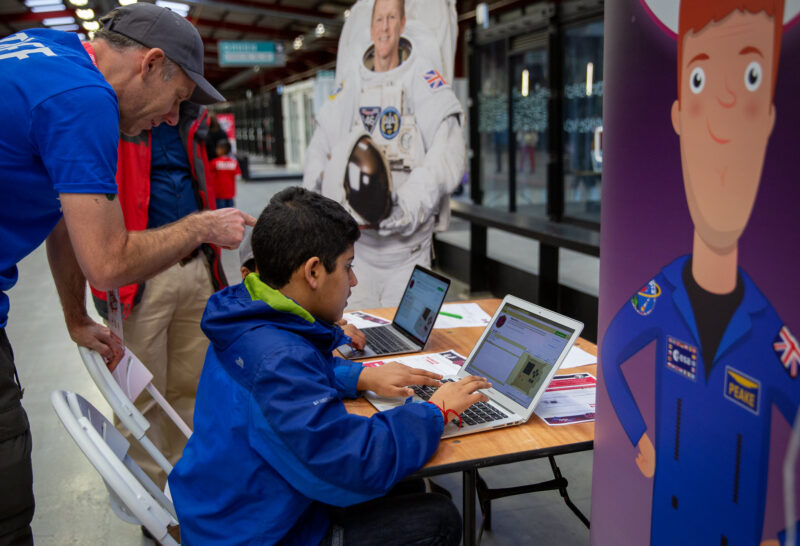
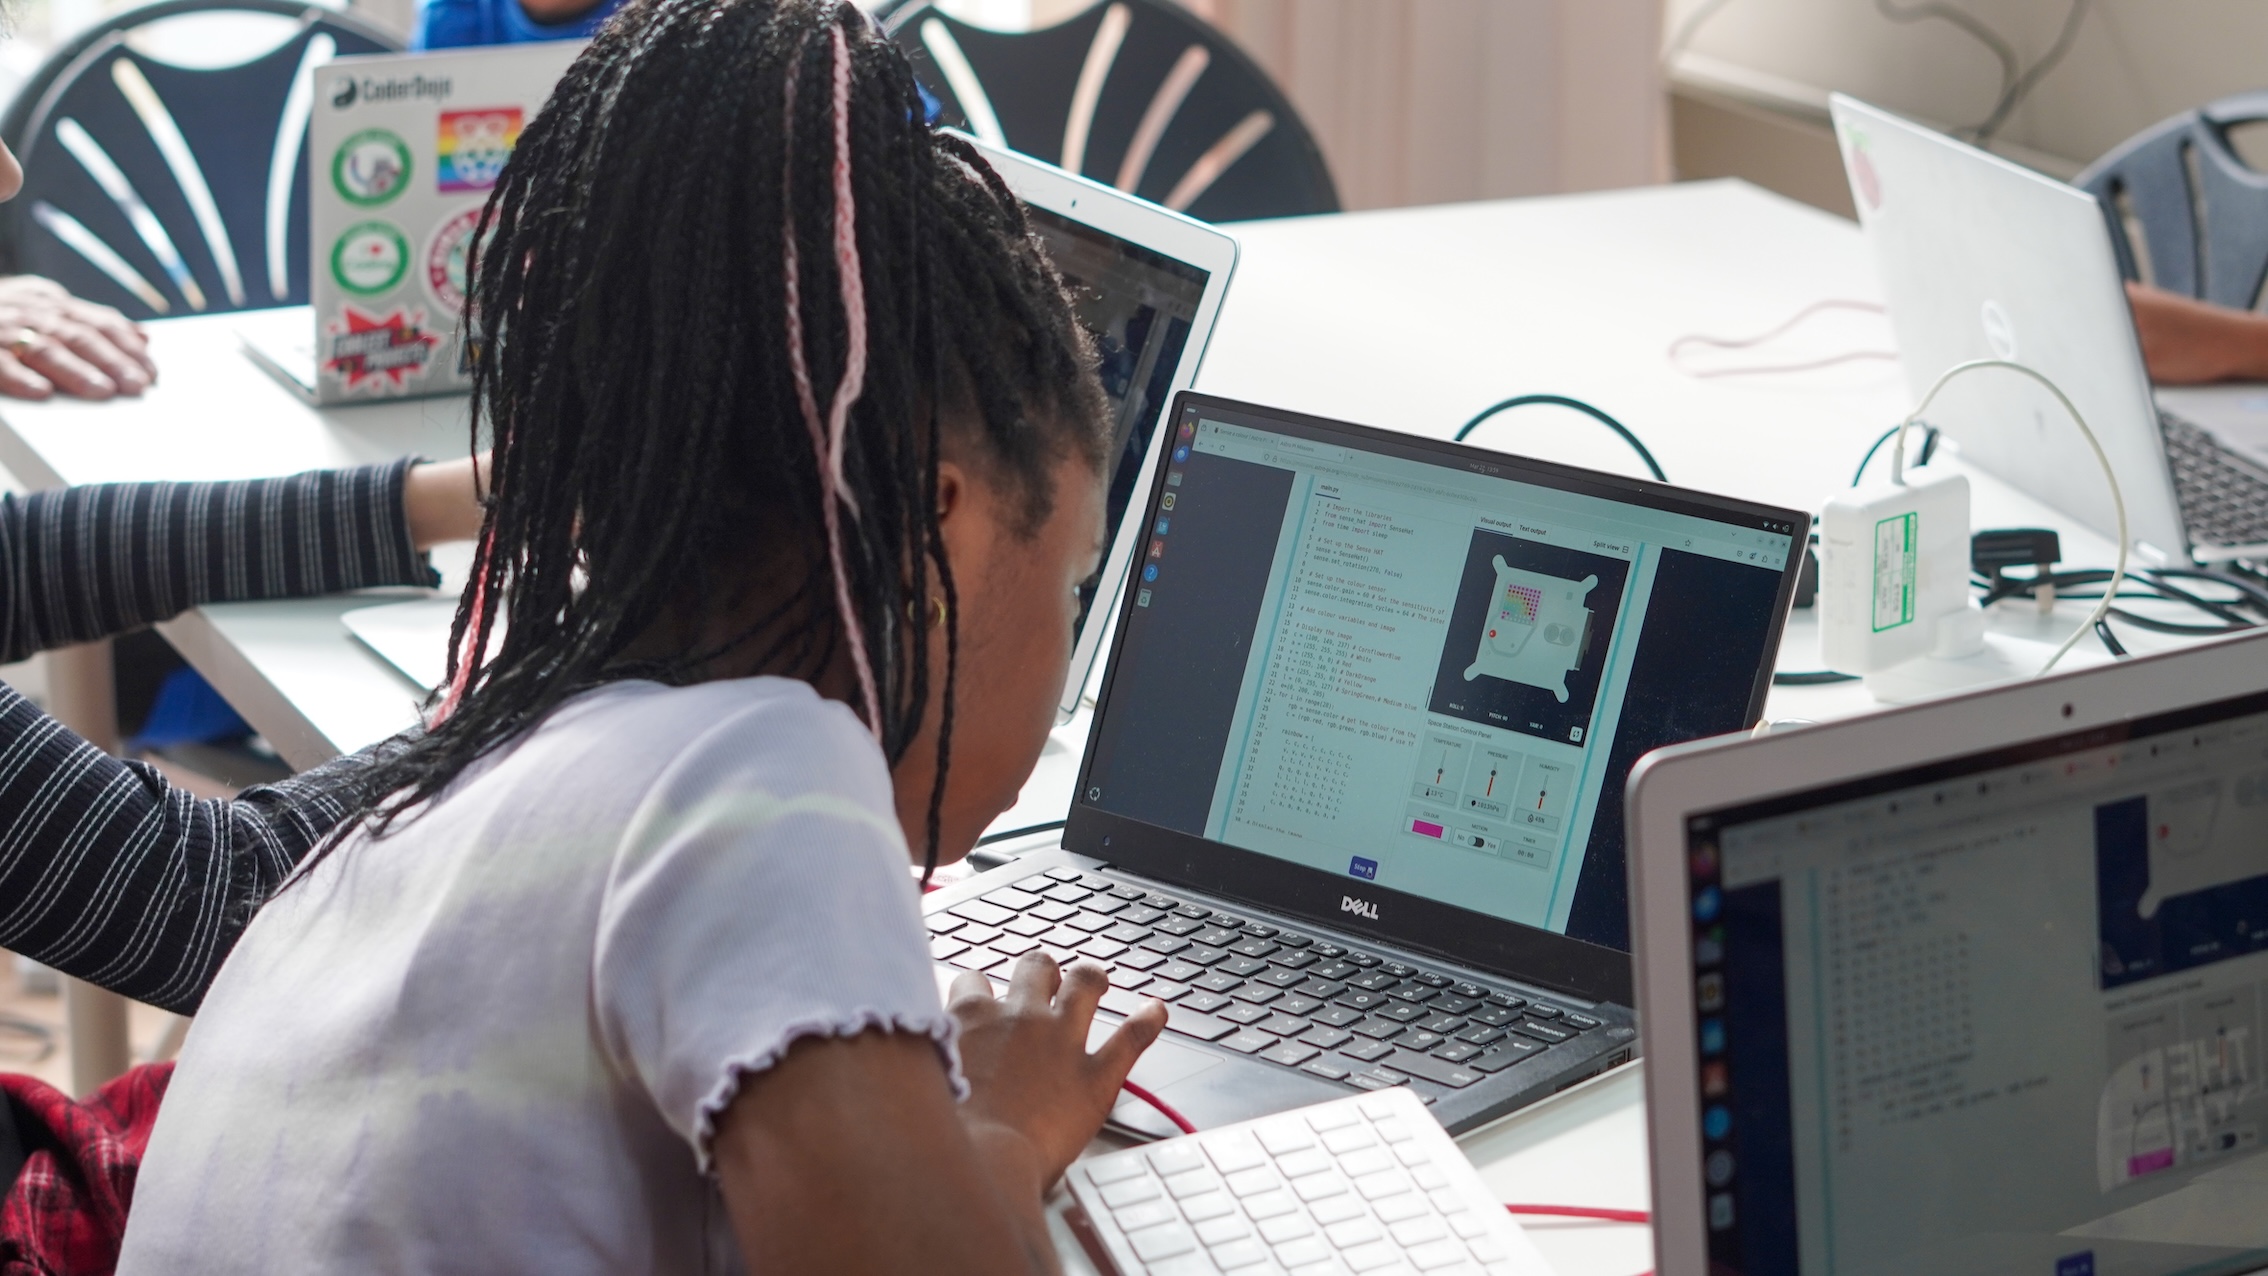
Not true! In the Astro Pi Challenge 2024/25, young people created over 17,800 computer programs that ran on board the International Space Station (ISS). Teams of young people aged between 8 and 19 took part in the challenge in a range of settings, including schools, Code Clubs, libraries, and community youth groups. They wrote short programs in Python, which were then sent to run on special Raspberry Pi computers, called Astro Pis, in the Columbus module of the ISS.
The Astro Pi computers up close.
Since the first Astro Pis arrived on the ISS in 2015, over 160,000 young people have had their code run in space. To celebrate their achievements, they each received certificates with the exact time and location of the ISS when their programs ran.
“We want our code to run in space! We are fascinated by discovery and the opportunity to contribute to a real science experiment on the ISS.” – Mission Space Lab mentor
Myth 2: Only experienced programmers can write code for the International Space Station
Not true! The Astro Pi Challenge is made up of two missions, Mission Zero and Mission Space Lab, and Mission Zero is perfect for young people who are new to text-based coding. With the help of step-by-step project instructions, young people write a short Python program to display personalised pixel art on board the ISS, using data from a sensor on one of the Astro Pi computers in their image.
In fact, Mission Zero mentors find that the low-stakes nature of the activity coupled with the real-world connection to space create an ideal learning environment. 83% of Mission Zero 2024/25 mentors told us that participation increased young people’s skills and confidence in computing and digital making, and 78% believed that young people were likely to participate in other computing or digital making challenges in the future.
“They [young people] come from complicated environments and sometimes their confidence is very low. They don’t believe in themselves and this [Mission Zero] really empowers them.” – Mission Zero mentor
Myth 3: Learning to write code for the ISS only involves technical skills
Not true! Mission Zero engages young people in thinking creatively as they plan their artwork, and Mission Space Lab involves working in teams to write a computer program to solve a scientific task in space, combining teamwork, problem-solving, and knowledge from other scientific domains. While 100% of mentors whose teams successfully completed Mission Space Lab in 2024/25 agreed that participation improved young people’s skills in computing and digital making, 91% also confirmed that it increased young people’s confidence in these areas, and 91% told us that it increased young people’s understanding of STEM concepts.
The impact likely goes beyond building skills. Mentors from both Astro Pi 2024/25 missions told us that the challenge made young people feel connected to a wider community of learners around the world, and the excitement of the challenge also extended to the mentors themselves, as well as other adults in their community.
“Mission Zero is a way of connecting not only to a worldwide group of learners, but also to explorers, future scientists, and future astronauts. To see them as part of a larger community and not just an activity or assignment that they have to do in class.” – Mission Zero mentor
An image sequence captured by team TheNinja during their Mission Space Lab experiment
Thank you to everyone who continues to make the Astro Pi Challenge a success. To find out more about the ways in which the challenge impacts young people, read the full Astro Pi 2024/25 impact report:
If you would like to find out more about how you and your creators can participate in this year’s European Astro Pi Challenge, read our launch blog post.
How do you find the root cause of a configuration management failure when you have a peak of hundreds of changes in 15 minutes on thousands of servers?
That was the challenge we faced as we built the infrastructure to reduce release delays due to failures of Salt, a configuration management tool. (We eventually reduced such failures on the edge by over 5%, as we’ll explain below.) We’ll explore the fundamentals of Salt, and how it is used at Cloudflare. We then describe the common failure modes and how they delay our ability to release valuable changes to serve our customers.
By first solving an architectural problem, we provided the foundation for self-service mechanisms to find the root cause of Salt failures on servers, datacenters and groups of datacenters. This system is able to correlate failures with git commits, external service failures and ad hoc releases. The result of this has been a reduction in the duration of software release delays, and an overall reduction in toilsome, repetitive triage for SRE.
To start, we will go into the basics of the Cloudflare network and how Salt operates within it. And then we’ll get to how we solved the challenge akin to finding a grain of sand in a heap of Salt.
How Salt works
Configuration management (CM) ensures that a system corresponds to its configuration information, and maintains the integrity and traceability of that information over time. A good configuration management system ensures that a system does not “drift” – i.e. deviate from the desired state. Modern CM systems include detailed descriptions of infrastructure, version control for these descriptions, and other mechanisms to enforce the desired state across different environments. Without CM, administrators must manually configure systems, a process that is error-prone and difficult to reproduce.
Salt is an example of such a CM tool. Designed for high-speed remote execution and configuration management, it uses a simple, scalable model to manage large fleets. As a mature CM tool, it provides consistency, reproducibility, change control, auditability and collaboration across team and organisational boundaries.
Salt’s design revolves around a master/minion architecture, a message bus built on ZeroMQ, and a declarative state system. (At Cloudflare we generally avoid the terms “master” and “minion.” But we will use them here because that’s how Salt describes its architecture.) The salt master is a central controller that distributes jobs and configuration data. It listens for requests on the message bus and dispatches commands to targeted minions. It also stores state files, pillar data and cache files. The salt minion is a lightweight agent installed on each managed host/server. Each minion maintains a connection to the master via ZeroMQ and subscribes to published jobs. When a job matches the minion, it executes the requested function and returns results.
The diagram below shows a simplification of the Salt architecture described in the docs, for the purpose of this blog post.
The state system provides declarative configuration management. States are often written in YAML and describe a resource (package, file, service, user, etc.) and the desired attributes. A common example is a package state, which ensures that a package is installed at a specified version.
States can call execution modules, which are Python functions that implement system actions. When applying states, Salt returns a structured result containing whether the state succeeded (result: True/False), a comment, changes made, and duration.
Salt at Cloudflare
We use Salt to manage our ever-growing fleet of machines, and have previously written about our extensive usage. The master-minion architecture described above allows us to push configuration in the form of states to thousands of servers, which is essential for maintaining our network. We’ve designed our change propagation to involve blast radius protection. With these protections in place, a highstate failure becomes a signal, rather than a customer-impacting event.
This release design was intentional – we decided to “fail safe” instead of failing hard. By further adding guardrails to safely release new code before a feature reaches all users, we are able to propagate a change with confidence that failures will halt the Salt deployment pipeline by default. However, every halt blocks other configuration deployments and requires human intervention to determine the root cause. This can quickly become a toilsome process as the steps are repetitive and bring no enduring value.
Part of our deployment pipeline for Salt changes uses Apt. Every X minutes a commit is merged into the master branch, per Y minutes those merges are bundled and deployed to APT servers. The key file to retrieving Salt Master configuration from that APT server is the APT source file:
# /etc/apt/sources.list.d/saltcodebase.sources
# MANAGED BY SALT -- DO NOT MODIFY

Types: deb
URIs: mirror+file:/etc/apt/mirrorlists/saltcodebase.txt
Suites: stable canary
Components: cloudflare
Signed-By: /etc/apt/keyrings/cloudflare.gpg
This file directs a master to the correct suite for its specific environment. Using that suite, it retrieves the latest package containing the relevant Salt Debian package with the latest changes. It installs that package and begins deploying the included configuration. As it deploys the configuration on machines, the machines report their health using Prometheus. If a version is healthy, it will be progressed into the next environment. Before it can be progressed, a version has to pass a certain soak threshold to allow a version to develop its errors, making more complex issues become apparent. That is the happy case.
The unhappy case brings a myriad of complications: As we do progressive deployments, if a version is broken, any subsequent version is also broken. And because broken versions are continuously overtaken by newer versions, we need to stop deployments altogether. In a broken version scenario, it is crucial to get a fix out as soon as possible. This touches upon the core question of this blog post: What if a broken Salt version is propagated across the environment, we are abandoning deployments, and we need to get a fix out as soon as possible?
The pain: how Salt breaks and reports errors (and how it affects Cloudflare)
While Salt aims for idempotent and predictable configuration, failures can occur during the render, compile, or runtime stages. These failures are commonly due to misconfiguration. Errors in Jinja templates or invalid YAML can cause the render stage to fail. Examples include missing colons, incorrect indentation, or undefined variables. A syntax error is often raised with a stack trace pointing to the offending line.
Another frequent cause of failure is missing pillar or grain data. Since pillar data is compiled on the master, forgetting to update pillar top files or refreshing pillar can result in KeyError exceptions. As a system that maintains order using requisites, misconfigured requisites can lead to states executing out-of-order or being skipped. Failures can also happen when minions are unable to authenticate with the master, or cannot reach the master due to network or firewall issues.
Salt reports errors in several ways. By default, the salt and salt-call commands exit with a retcode 1 when any state fails. Salt also sets internal retcodes for specific cases: 1 for compile errors, 2 when a state returns False, and 5 for pillar compilation errors. Test mode shows what changes would be made without actually executing them, but is useful for catching syntax or ordering issues. Debug logs can be toggled using the -l debug CLI option (salt <minion> state.highstate -l debug).
The state return also includes the details of the individual state failures – the durations, timestamps, functions and results. If we introduce a failure to the file.managed state by referencing a file that doesn’t exist in the Salt fileserver, we see this failure:
web1:
----------
          ID: nginx
    Function: pkg.installed
      Result: True
     Comment: Package nginx is already installed
     Started: 15:32:41.157235
    Duration: 256.138 ms
     Changes:

----------
          ID: /etc/nginx/nginx.conf
    Function: file.managed
      Result: False
     Comment: Source file salt://webserver/files/nginx.conf not found in saltenv 'base'
     Started: 15:32:41.415128
    Duration: 14.581 ms
     Changes:

Summary for web1
------------
Succeeded: 1 (changed=0)
Failed:    1
------------
Total states run:     2
Total run time: 270.719 ms
The flexibility of the output format means that humans can parse them in custom scripts. But more importantly, it can also be consumed by more complex, interconnected automation systems. We knew we could easily parse these outputs to attribute the cause of a Salt failure with an input – e.g. a change in source control, an external service failure, or a software release. But something was missing.
The solutions
Configuration errors are a common cause of failure in large-scale systems. Some of these could even lead to full system outages, which we prevent with our release architecture. When a new release or configuration breaks in production, our SRE team needs to find and fix the root cause to avoid release delays. As we’ve previously noted, this triage is tedious and increasingly difficult due to system complexity.
While some organisations use formal techniques such as automated root cause analysis, most triage is still frustratingly manual. After evaluating the scope of the problem, we decided to adopt an automated approach. This section describes the step-by-step approach to solving this broad, complex problem in production.
Phase one: retrievable CM inputs
When a Salt highstate fails on a minion, SRE teams faced a tedious investigation process: manually SSHing into minions, searching through logs for error messages, tracking down job IDs (JIDs), and locating the job associated with the JID on one of multiple associated masters. This is all while racing against a 4-hour retention window on master logs. The fundamental problem was architectural: Job results live on Salt Masters, not on the minions where they’re executed, forcing operators to guess which master processed their job (SSHing into each one) and limiting visibility for users without master access.
We built a solution that caches job results directly on minions, similar to the local_cache returner that exists for masters. That enables local job retrieval and extended retention periods. This transformed a multistep, time-sensitive investigation into a single query — operators can retrieve job details, automatically extract error context, and trace failures back to specific file changes and commit authors, all from the minion itself. The custom returner filters and manages cache size intelligently, eliminating the “which master?” problem while also enabling automated error attribution, reducing time to resolution, and removing human toil from routine troubleshooting.
By decentralizing job history and making it queryable at the source, we moved significantly closer to a self-service debugging experience where failures are automatically contextualized and attributed, letting SRE teams focus on fixes rather than forensics.
Phase two: Self-service using a Salt Blame Module
Once job information was available on the minion, we no longer needed to resolve which master triggered the job that failed. The next step was to write a Salt execution module that would allow an external service to query for job information, and more specifically failed job information, without needing to know Salt internals. This led us to write a module called Salt Blame. Cloudflare prides itself on its blameless culture, our software on the other hand…
The blame module is responsible for pulling together three things:
Local job history information
CM inputs (latest commit present during the job)
Git repo commit history
We chose to write an execution module for simplicity, decoupling external automation from the need to understand Salt internals, and potential usage by operators for further troubleshooting. Writing execution modules is already well established within operational teams and adheres to well-defined best practices such as unit tests, linting and extensive peer-review.
The module is understandably very simple. It iterates in reverse chronological order through the jobs in the local cache and looks for the first job failure chronologically, and then the successful job immediately prior to it. This is for no other reason than narrowing down the true first failure and giving us before and after state results. At this stage, we have several avenues to present context to the caller: To find possible commit culprits, we look through all commits between the last successful Job ID and the failure to determine if any of these changed files relevant to the failure. We also provided the list of failed states and their outputs as another avenue to spot the root cause. We’ve learned that this flexibility is important to cover the wide range of failure possibilities.
We also make a distinction between normal failed states, and compile errors. As described in the Salt docs, each job returns different retcodes based on the outcome.
Compile Error: 1 is set when any error is encountered in the state compiler.
Failed State: 2 is set when any state returns a False result.
Most of our failures manifest as failed states as a result of a change in source control. An engineer building a new feature for our customers may unintentionally introduce a failure that was uncaught by our CI and Salt Master tests. In the first iteration of the module, listing all the failed states was sufficient to pinpoint the root cause of a highstate failure.
However, we noticed that we had a blind spot. Compile errors do not result in a failed state, since no state runs. Since these errors returned a different retcode from what we checked for, the module was completely blind to them. Most compile errors happen when a Salt service dependency fails during the state compile phase. They can also happen as a result of a change in source control, although that is rare.
With both state failures and compile errors accounted for, we drastically improved our ability to pinpoint issues. We released the module to SREs who immediately realised the benefits of faster Salt triage.
# List all the recent failed states
minion~$ salt-call -l info blame.last_failed_states
local:
    |_
      ----------
      __id__:
          /etc/nginx/nginx.conf
      __run_num__:
          5221
      __sls__:
          foo
      changes:
          ----------
      comment:
          Source file salt://webserver/files/nginx.conf not found in saltenv 'base'
      duration:
          367.233
      finish_time_stamp:
          2025-10-22T10:00:17.289897+00:00
      fun:
          file.managed
      name:
          /etc/nginx/nginx.conf
      result:
          False
      start_time:
          10:00:16.922664
      start_time_stamp:
          2025-10-22T10:00:16.922664+00:00

# List all the commits that correlate with a failed state
minion~$ salt-call -l info blame.last_highstate_failure
local:
    ----------
    commits:
        |_
          ----------
          author_email:
              [email protected]
          author_name:
              John Doe
          commit_datetime:
              2025-06-30T15:29:26.000+00:00
          commit_id:
              e4a91b2c9f7d3b6f84d12a9f0e62a58c3c7d9b5a
          path:
              /srv/salt/webserver/init.sls
    message:
        reviewed 5 change(s) over 12 commit(s) looking for 1 state failure(s)
    result:
        True

# List all the compile errors
minion~$ salt-call -l info blame.last_compile_errors
local:
    |_
      ----------
      error_types:
      job_timestamp:
          2025-10-24T21:55:54.595412+00:00
      message: A service failure has occured
      state: foo
      traceback:
          Full stack trace of the failure
      urls: http://url-matching-external-service-if-found
Phase three: automate, automate, automate!
Faster triage is always a welcome development, and engineers were comfortable running local commands on minions to triage Salt failures. But in a busy shift, time is of the essence. When failures spanned across multiple datacenters or machines, it easily became cumbersome to run commands across all these minions. This solution also required context-switches between multiple nodes and datacenters. We needed a way to aggregate common failure types using a single command – single minions, pre-production datacenters and production datacenters.
We implemented several mechanisms to simplify triage and eliminate manual triggers. We aimed to get this tooling as close to the triage location as possible, which is often chat. With three distinct commands, engineers were now able to triage Salt failures right from chat threads.
With a hierarchical approach, we made individual triage possible for minions, data centers and groups of data centers. A hierarchy makes this architecture fully extensible, flexible and self-organising. An engineer is able to triage a failure on one minion, and at the same time the entire data center as needed.
The ability to triage multiple data centers at the same time became immediately useful for tracking the root cause of failures in pre-production data centers. These failures delay the propagation of changes to other data centers, and hinder our ability to release changes for customer features, bug fixes or incident remediation. The addition of this triage option has cut down the time to debug and remediate Salt failures by over 5%, allowing us to consistently release important changes for our customers.
While 5% does not immediately look like a drastic improvement, the magic is in the cumulative effect. We won’t release actual figures of the amount of time releases are delayed for, but we can do a simple thought experiment. If the average amount of time spent is even just 60 minutes per day, a reduction by 5% saves us 90 minutes (one hour 30 minutes) per month.
Another indirect benefit lies in more efficient feedback loops. Since engineers spend less time fiddling with complex configurations, that energy is diverted towards preventing reoccurrence, further reducing the overall time by an immeasurable amount. Our future plans include measurement and data analytics to understand the outcomes of these direct and indirect feedback loops.
The image below shows an example of pre-production triage output. We are able to correlate failures with git commits, releases, and external service failures. During a busy shift, this information is invaluable for quickly fixing breakage. On average, each minion “blame” takes less than 30 seconds, while multiple data centers are able to return a result in a minute or less.
The image below describes the hierarchical model. Each step in the hierarchy is executed in parallel, allowing us to achieve blazing fast results.
With these mechanisms available, we further cut down triage time by triggering the triage automation on known conditions, especially those with impact to the release pipeline. This directly improved the velocity of changes to the edge since it took less time to find a root cause and fix-forward or revert.
Phase four: measure, measure, measure
After we got blazing fast Salt triage, we needed a way to measure the root causes. While individual root causes are not immediately valuable, historical analysis was deemed important. We wanted to understand the common causes of failure, especially as they hinder our ability to deliver value to customers. This knowledge creates a feedback loop that can be used to keep the number of failures low.
Using Prometheus and Grafana, we track the top causes of failure: git commits, releases, external service failures and unattributed failed states. The list of failed states is particularly useful because we want to know repeat offenders and drive better adoption of stable releasing practices. We are also particularly interested in root causes — a spike in the number of failures due to git commits indicates a need to adopt better coding practices and linting, a spike in external service failures indicates a regression in an internal system to be investigated, and a spike in release-based failures indicates a need for better gating and release-shepherding.
We analyse these metrics on a monthly cycle, providing feedback mechanisms through internal tickets and escalations. While the immediate impact of these efforts is not yet visible as the efforts are nascent, we expect to improve the overall health of our Saltstack infrastructure and release process by reducing the amount of breakage we see.
The broader picture
Much of operational work is often seen as a “necessary evil”. Humans in ops are conditioned to intervene when failures happen and remediate them. This cycle of alert-response is necessary to keep the infrastructure running, but it often leads to toil. We have discussed the effect of toil in a previous blog post.
This work represents another step in the right direction – removing more toil for our on-call SREs, and freeing up valuable time to work on novel issues. We hope that this encourages other operations engineers to share the progress they are making towards reducing overall toil in their organizations. We also hope that this sort of work can be adopted within Saltstack itself, although the lack of homogeneity in production systems across several companies makes it unlikely.
In the future, we plan to improve the accuracy of detection and rely less on external correlation of inputs to determine the root cause of failed outcomes. We will investigate how to move more of this logic into our native Saltstack modules, further streamlining the process and avoiding regressions as external systems drift.
If this sort of work is exciting to you, we encourage you to take a look at our careers page.
The Business of Secrets: Adventures in Selling Encryption Around the World by Fred Kinch (May 24, 2024)
From the vantage point of today, it’s surreal reading about the commercial cryptography business in the 1970s. Nobody knew anything. The manufacturers didn’t know whether the cryptography they sold was any good. The customers didn’t know whether the crypto they bought was any good. Everyone pretended to know, thought they knew, or knew better than to even try to know.
The Business of Secrets is the self-published memoirs of Fred Kinch. He was founder and vice president of—mostly sales—at a US cryptographic hardware company called Datotek, from company’s founding in 1969 until 1982. It’s mostly a disjointed collection of stories about the difficulties of selling to governments worldwide, along with descriptions of the highs and (mostly) lows of foreign airlines, foreign hotels, and foreign travel in general. But it’s also about encryption.
Datotek sold cryptographic equipment in the era after rotor machines and before modern academic cryptography. The company initially marketed computer-file encryption, but pivoted to link encryption—low-speed data, voice, fax—because that’s what the market wanted.
These were the years where the NSA hired anyone promising in the field, and routinely classified—and thereby blocked—publication of academic mathematics papers of those they didn’t hire. They controlled the fielding of strong cryptography by aggressively using the International Traffic in Arms regulation. Kinch talks about the difficulties in getting an expert license for Datotek’s products; he didn’t know that the only reason he ever got that license was because the NSA was able to break his company’s stuff. He had no idea that his largest competitor, the Swiss company Crypto AG, was owned and controlled by the CIA and its West German equivalent. “Wouldn’t that have made our life easier if we had known that back in the 1970s?” Yes, it would. But no one knew.
Glimmers of the clandestine world peek out of the book. Countries like France ask detailed tech questions, borrow or buy a couple of units for “evaluation,” and then disappear again. Did they break the encryption? Did they just want to see what their adversaries were using? No one at Datotek knew.
Kinch “carried the key generator logic diagrams and schematics” with him—even today, it’s good practice not to rely on their secrecy for security—but the details seem laughably insecure: four linear shift registers of 29, 23, 13, and 7 bits, variable stepping, and a small nonlinear final transformation. The NSA probably used this as a challenge to its new hires. But Datotek didn’t know that, at the time.
Kinch writes: “The strength of the cryptography had to be accepted on trust and only on trust.” Yes, but it’s so, so weird to read about it in practice. Kinch demonstrated the security of his telephone encryptors by hooking a pair of them up and having people listen to the encrypted voice. It’s rather like demonstrating the safety of a food additive by showing that someone doesn’t immediately fall over dead after eating it. (In one absolutely bizarre anecdote, an Argentine sergeant with a “hearing defect” could understand the scrambled analog voice. Datotek fixed its security, but only offered the upgrade to the Argentines, because no one else complained. As I said, no one knew anything.)
In his postscript, he writes that even if the NSA could break Datotek’s products, they were “vastly superior to what [his customers] had used previously.” Given that the previous devices were electromechanical rotor machines, and that his primary competition was a CIA-run operation, he’s probably right. But even today, we know nothing about any other country’s cryptanalytic capabilities during those decades.
A lot of this book has a “you had to be there” vibe. And it’s mostly tone-deaf. There is no real acknowledgment of the human-rights-abusing countries on Datotek’s customer list, and how their products might have assisted those governments. But it’s a fascinating artifact of an era before commercial cryptography went mainstream, before academic cryptography became approved for US classified data, before those of us outside the triple fences of the NSA understood the mathematics of cryptography.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.