On Sunday, September 28, 2025, the Republic of Moldova held a parliamentary election that was described as a referendum on its geopolitical future. The election was conducted amid claims of Russian interference, both online and offline. Ensuring the security of the election infrastructure was a critical priority, not just to protect the vote count, but to guarantee the system’s resilience so that all Moldovans could access authoritative information about the election.
We were proud to support the Moldovan Central Election Commission (CEC) ahead of their September 28th election. Consistent with public reporting, cyberattacks were not the story; the focus remained on the democratic process. We want to share what we found as we provided assistance to the CEC on election day.
Elections in Moldova
The 2025 elections in Moldova were viewed by many as a defining moment for the country. Specifically, it pitted the countries’ pro-European government against an opposition seeking closer alignment with Russia. The entire election process was carried out under intense pressure from foreign interference, employing a wide range of hybrid tactics. Beyond disinformation and illegal funding, the Moldovan state faced constant digital threats and was on high alert for planned post-election violence aimed at promoting distrust in the country’s democratic institutions. For the nation, ensuring the security and integrity of the election was a priority.
Several days before the election, Cloudflare onboarded the Moldova Central Election Commission (CEC), amid concerns over increasing cyberattacks. Since 2017, through the Athenian Project, we have provided protection to over 450 state and local government election entities in the United States. We were able to provide this expertise to the CEC and in less than a week we onboarded many of their election websites and quickly deployed mitigation strategies to help prepare them for election day.
Cyber attacks to the Moldova Election Commission
Cloudflare data shows that the Moldovan Election Commission experienced significant cyber attacks during the recent elections. From September 27 to September 29, 2025, our data shows how Moldovan citizens used the Internet to follow the political process and highlights the efforts by malicious actors to disrupt key election services.
For example, on September 28, 2025, the Moldovan Central Election Commission (CEC) experienced a series of concentrated, high-volume (DDoS) attacks strategically timed throughout the day. The attack began in the morning at 09:06:00 UTC and lasted for over twelve hours and ended as the official result reporting was underway at 21:34:00 UTC. In total, we mitigated over 898 million malicious requests directed at the CEC over the twelve-hour period.
Cloudflare systems categorized this activity into 11 attack “chunks” — which is a term used to denote a multi-wave pattern indicating a sophisticated attack. These initial bursts began during peak afternoon voting hours, with one of the most intense chunks, Chunk 5, striking before the polls closed at 15:31:00 UTC and hitting the largest recorded peak of 324,333 requests per second (rps).
Malicious traffic continued after the polls officially closed (18:00 UTC), directly targeting the result reporting phase. Multiple sustained waves, including attacks that peaked at over 243,000 rps, were mitigated. Fortunately, Cloudflare’s automated defenses successfully stopped the attacks in real-time, ensuring the CEC website remained online and accessible for Moldovan citizens.
The Moldovan government confirmed the attacks, as the Information Technology and Cybersecurity Service (STISC) reported a wide-ranging campaign targeting the CEC.md platform, government cloud systems, and diaspora voting stations. STISC also confirmed that the attacks were successfully neutralized, without any impact on the availability or integrity of electoral services.
“On behalf of the Information Technology and Cybersecurity Service (STISC), the institution technically responsible for ensuring cybersecurity of the electoral process conducted by the Central Electoral Commission of the Republic of Moldova on 28 September, we would like to extend our sincere gratitude for your outstanding support. We truly appreciate the opportunity to use your advanced systems and enterprise licenses during this critical period. Despite facing numerous DDoS attacks, thanks to your effective protection, no service interruptions were experienced, and the public remained unaffected.” – STISC Team, Information Technology and Cybersecurity Service, Republic of Moldova
“Cloudflare’s support was essential for Moldova’s parliamentary elections, ensuring uninterrupted access to real-time results for citizens at home and abroad. Their resilient infrastructure allowed us to withstand heavy DDoS attacks and protect the integrity of the democratic process.” – Anatolie Golovco, Cybersecurity and Digital Transformation Expert in the Office of the Prime Minister of Moldova
Other democracy, media and civic related targets under attack
While the Central Election Commission was the primary target, it was not the only one. On September 28, 2025, Cloudflare mitigated hundreds of millions of malicious requests aimed at Moldovan election-related, civil society and news websites. The Commission’s site absorbed the largest share, peaking near 900 million requests in a single day. But it wasn’t alone: a civic participation portal, democracy related services, a relevant broadcaster, and independent news outlets also saw significant DDoS traffic. As the chart shows, these combined attacks created a surge of hostile traffic on election day, showing what seems to be a campaign against both official institutions and public information channels.
One particularly intense application-layer wave hit a democracy-related parliamentary site, peaking at over 243,000 requests per second.
These attack patterns mirrored those against the election authority, suggesting a coordinated effort to disrupt both official election processes and the public information channels voters rely on. Cloudflare’s automated protections mitigated these multi-wave attacks in real time, keeping critical information channels available throughout the electoral timeline.
Securing the democratic process
Democracies around the world are increasingly targeted by cyberattacks. Through our Impact programs, we strive to keep websites vital to democracy — like voter registration sites, election information portals, campaign websites, and news sites — secure and available. From monitoring traffic patterns to mitigating cyberattacks, Cloudflare has observed trends that show the importance of online services during elections and the increasing attacks targeting them.
In the Moldovan parliamentary elections, the pro-Western governing party won a clear majority, defeating pro-Russian groups. We are proud to have provided services to the Moldovan Central Election Commission in securing the vote, ensuring that citizens—not malicious actors—determined the country’s future. To learn more about the Athenian Project, visit: https://www.cloudflare.com/athenian/
Imagine building AI applications that deliver accurate, current information without the complexity of developing intricate data retrieval systems. Today, we’re excited to announce the general availability of Web Grounding, a new built-in tool for Nova models on Amazon Bedrock.
Web Grounding provides developers with a turnkey Retrieval Augmented Generation (RAG) option that allows the Amazon Nova foundation models to intelligently decide when to retrieve and incorporate relevant up-to-date information based on the context of the prompt. This helps to ground the model output by incorporating cited public sources as context, aiming to reduce hallucinations and improve accuracy.
When should developers use Web Grounding?
Developers should consider using Web Grounding when building applications that require access to current, factual information or need to provide well-cited responses. The capability is particularly valuable across a range of applications, from knowledge-based chat assistants providing up-to-date information about products and services, to content generation tools requiring fact-checking and source verification. It’s also ideal for research assistants that need to synthesize information from multiple current sources, as well as customer support applications where accuracy and verifiability are crucial.
Web Grounding is especially useful when you need to reduce hallucinations in your AI applications or when your use case requires transparent source attribution. Because it automatically handles the retrieval and integration of information, it’s an efficient solution for developers who want to focus on building their applications rather than managing complex RAG implementations.
Getting started Web Grounding seamlessly integrates with supported Amazon Nova models to handle information retrieval and processing during inference. This eliminates the need to build and maintain complex RAG pipelines, while also providing source attributions that verify the origin of information.
Let’s see an example of asking a question to Nova Premier using Python to call the Amazon Bedrock Converse API with Web Grounding enabled.
First, I created an Amazon Bedrock client using AWS SDK for Python (Boto3) in the usual way. For good practice, I’m using a session, which helps to group configurations and make them reusable. I then create a BedrockRuntimeClient.
I then prepare the Amazon Bedrock Converse API payload. It includes a “role” parameter set to “user”, indicating that the message comes from our application’s user (compared to “assistant” for AI-generated responses).
For this demo, I chose the question “What are the current AWS Regions and their locations?” This was selected intentionally because it requires current information, making it useful to demonstrate how Amazon Nova can automatically invoke searches using Web Grounding when it determines that up-to-date knowledge is needed.
# Prepare the conversation in the format expected by Bedrock
question = "What are the current AWS regions and their locations?"
conversation = [
   {
     "role": "user",  # Indicates this message is from the user
     "content": [{"text": question}],  # The actual question text
      }
    ]
First, let’s see what the output is without Web Grounding. I make a call to Amazon Bedrock Converse API.
# Make the API call to Bedrock
model_id = "us.amazon.nova-premier-v1:0"
response = client.converse(
    modelId=model_id, # Which AI model to use
    messages=conversation, # The conversation history (just our question in this case)
    )
print(response['output']['message']['content'][0]['text'])
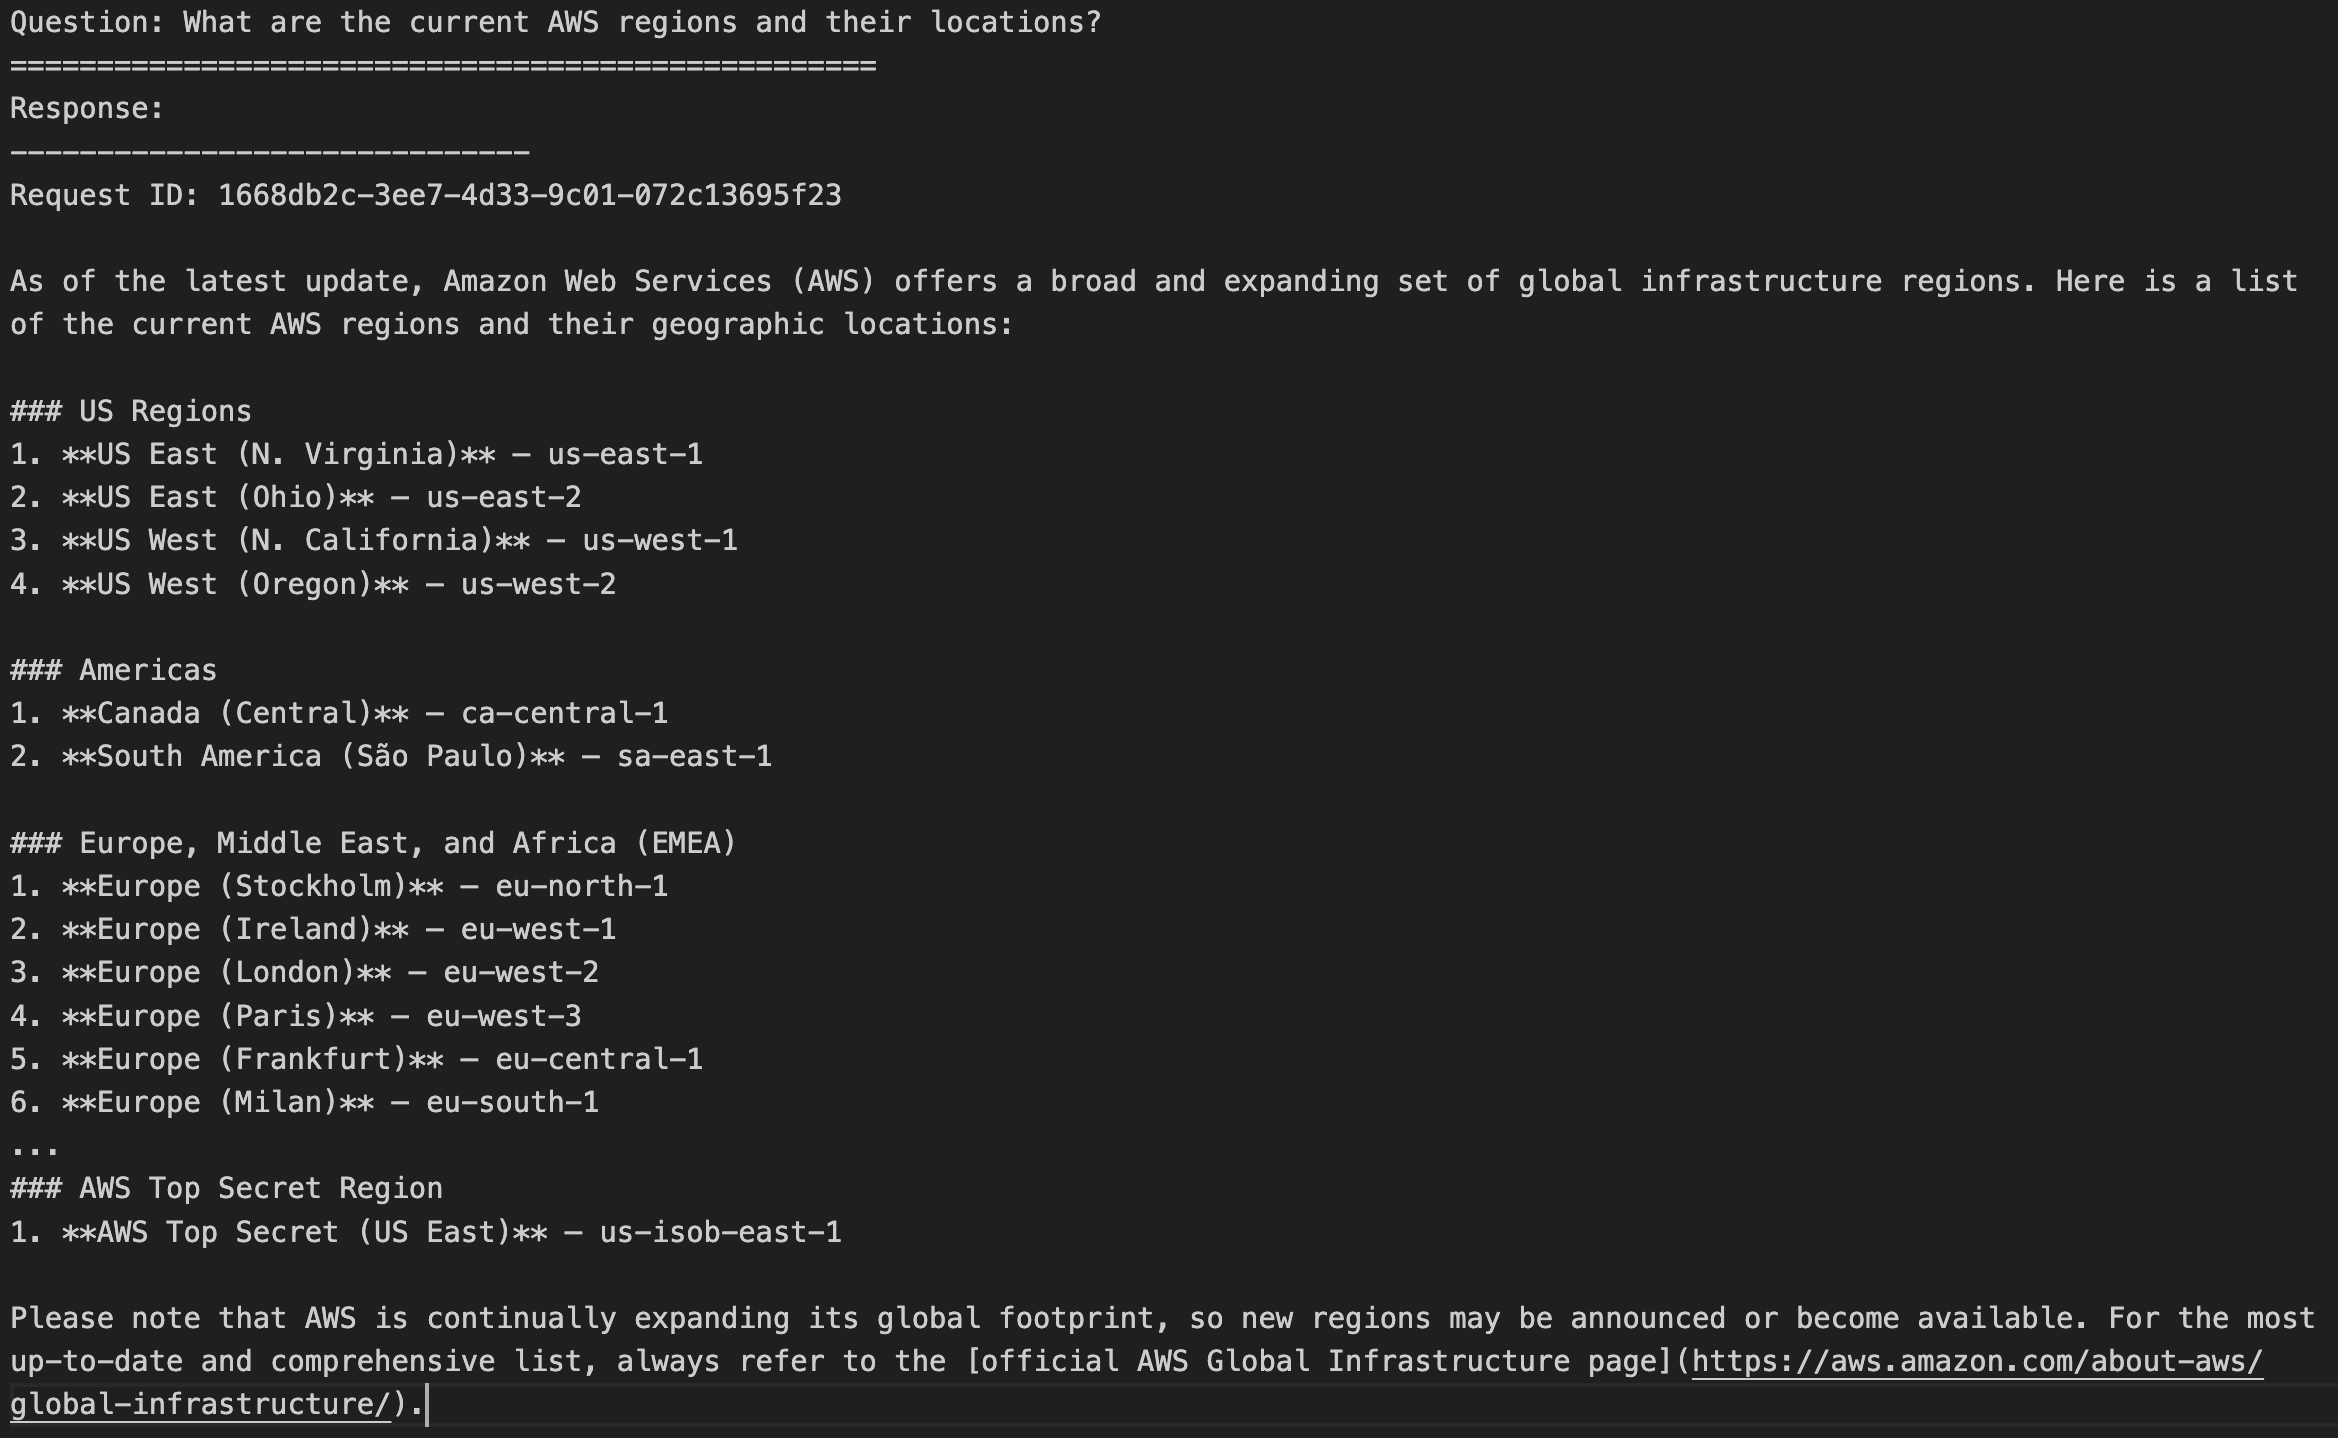
I get a list of all the current AWS Regions and their locations.
Now let’s use Web Grounding. I make a similar call to the Amazon Bedrock Converse API, but declare nova_grounding as one of the tools available to the model.
model_id = "us.amazon.nova-premier-v1:0"
response = client.converse(
    modelId=model_id,
    messages=conversation,
    toolConfig= {
          "tools":[
              {
                "systemTool": {
                   "name": "nova_grounding" # Enables the model to search real-time information
                 }
              }
          ]
     }
)
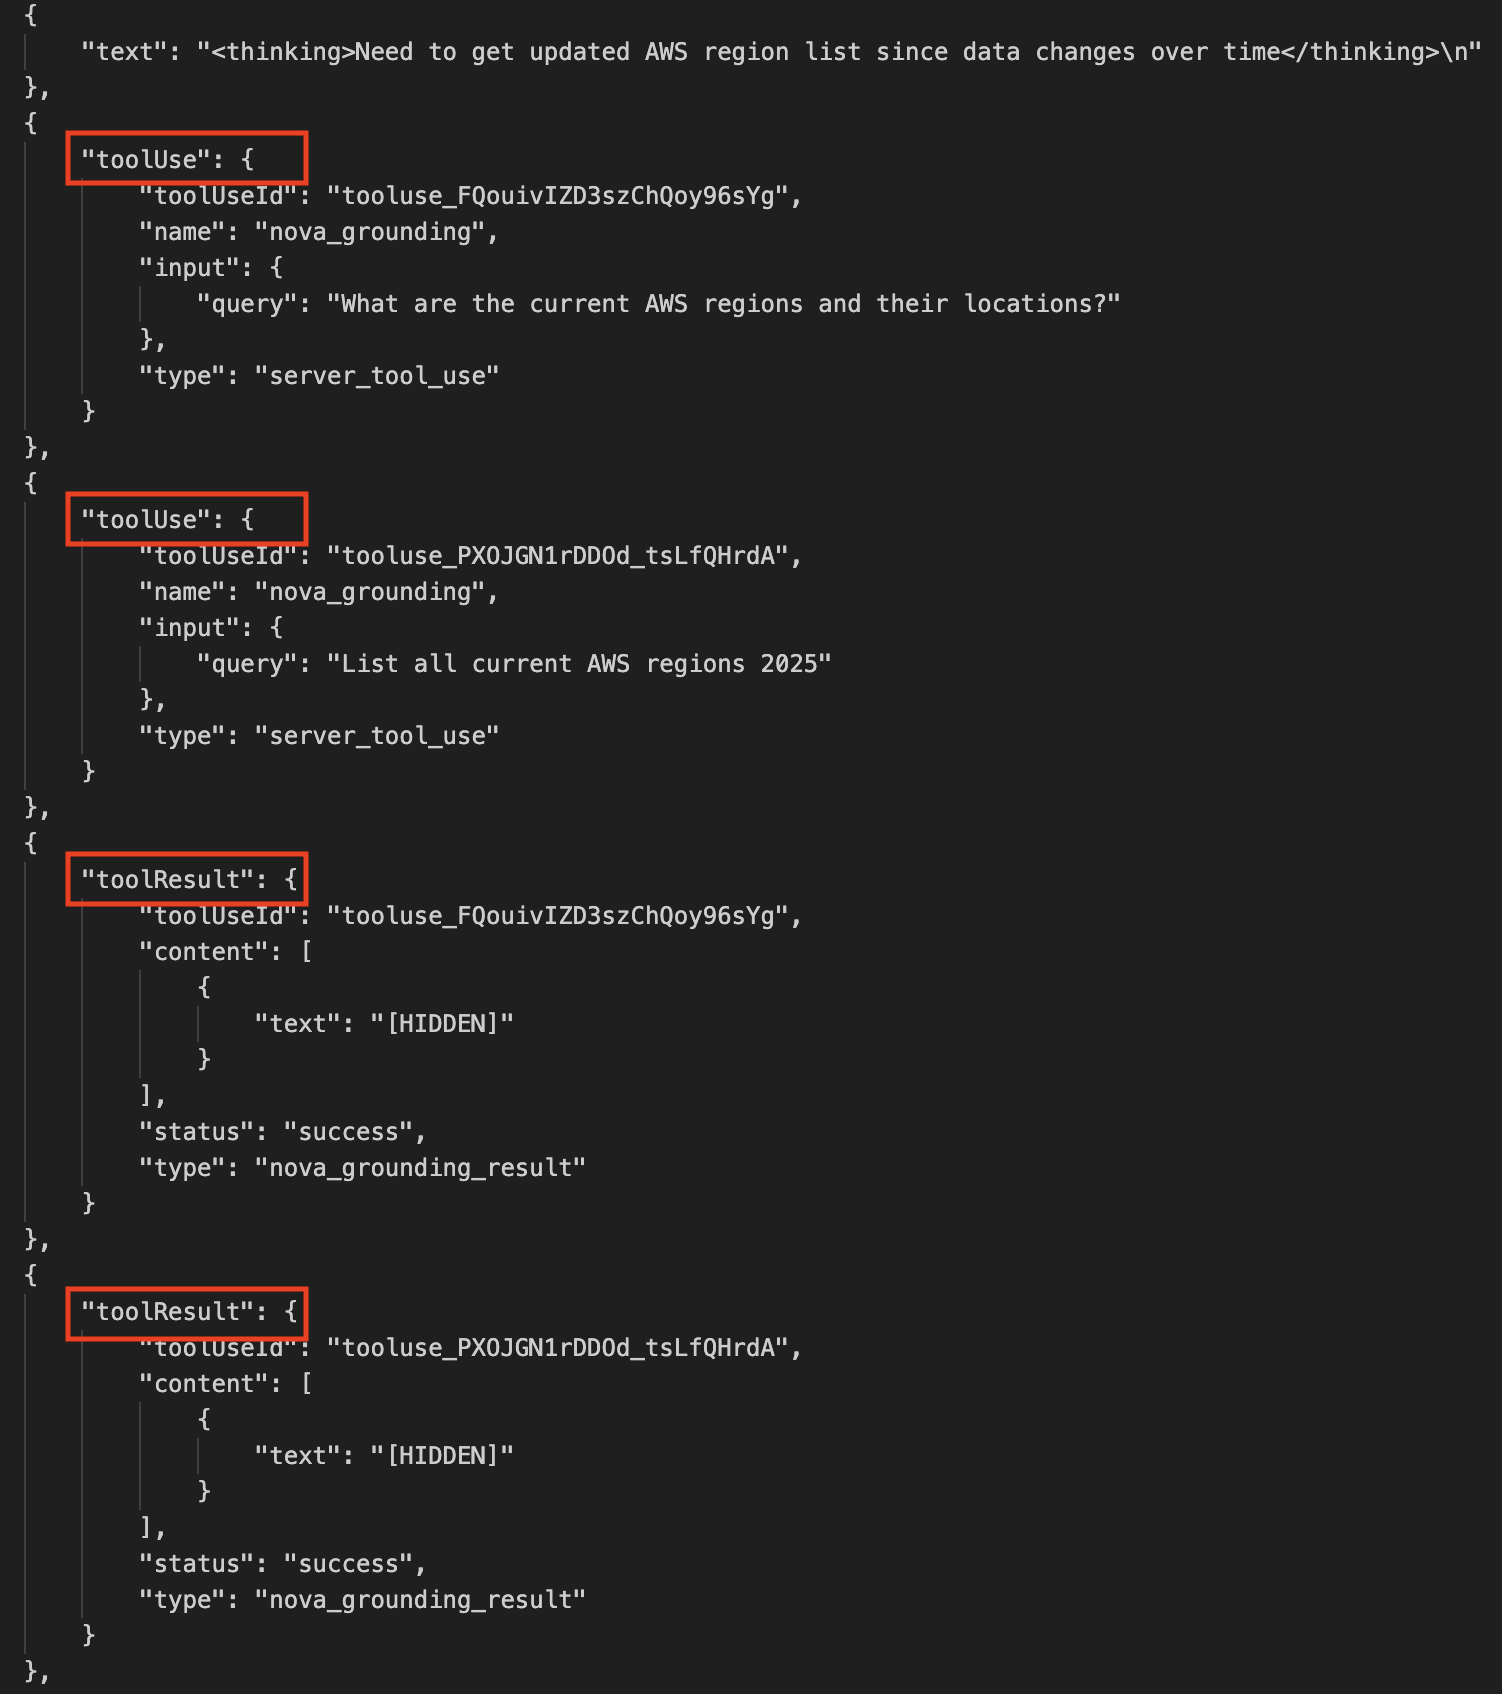
After processing the response, I can see that the model used Web Grounding to access up-to-date information. The output includes reasoning traces that I can use to follow its thought process and see where it automatically queried external sources. The content of the responses from these external calls appear as [HIDDEN] – a standard practice in AI systems that both protects sensitive information and helps manage output size.
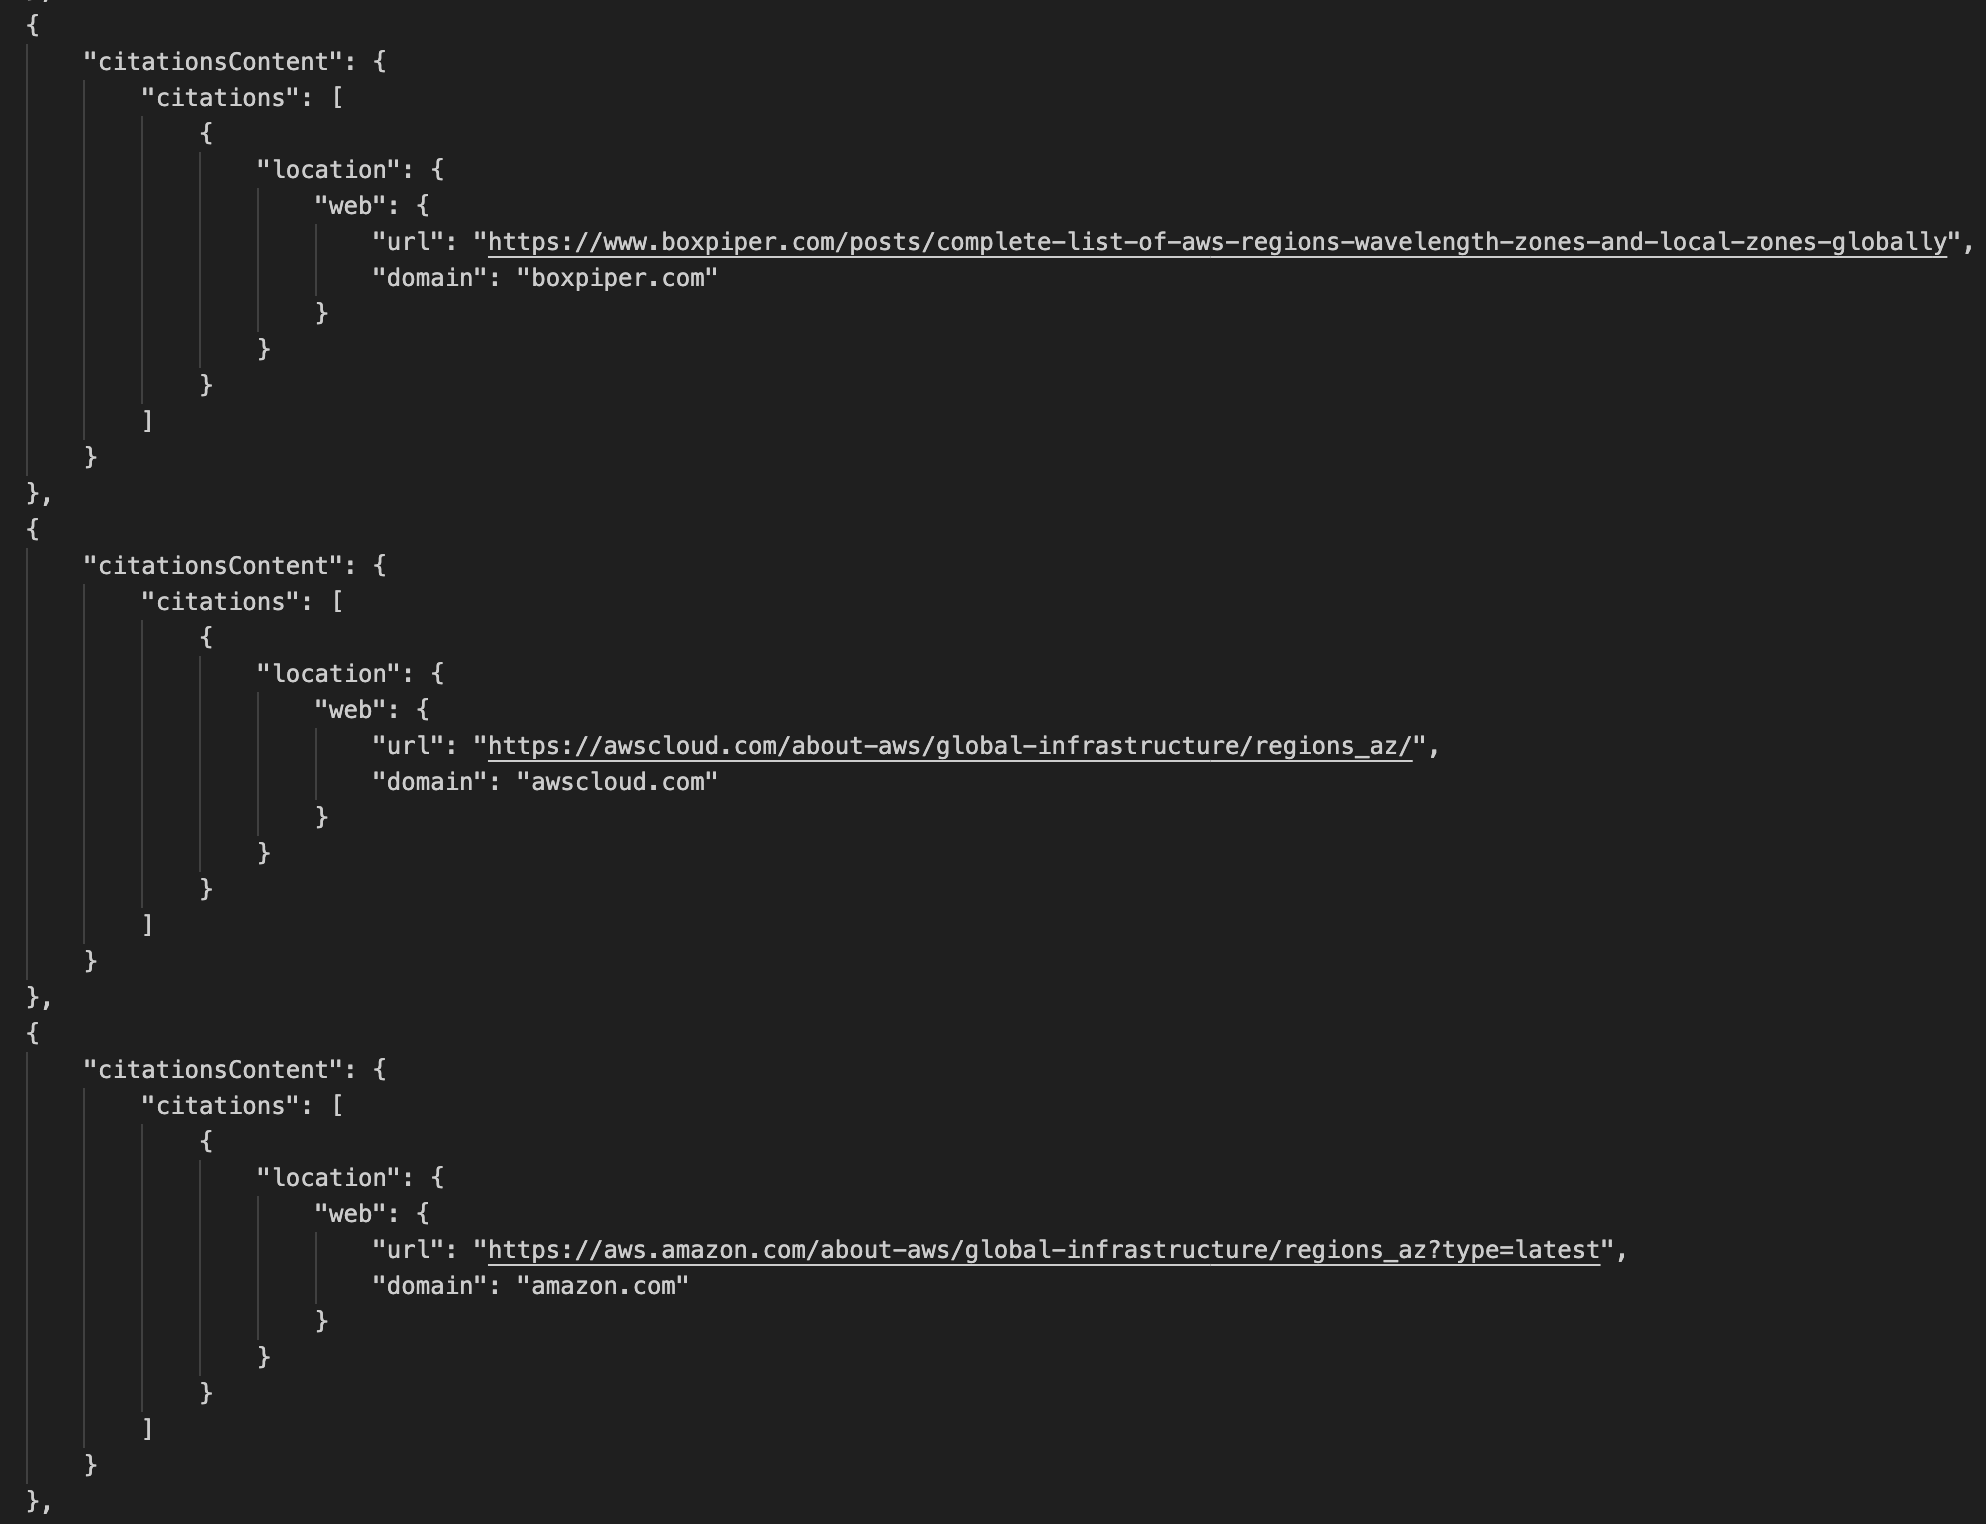
Additionally, the output also includes citationsContent objects containing information about the sources queried by Web Grounding.
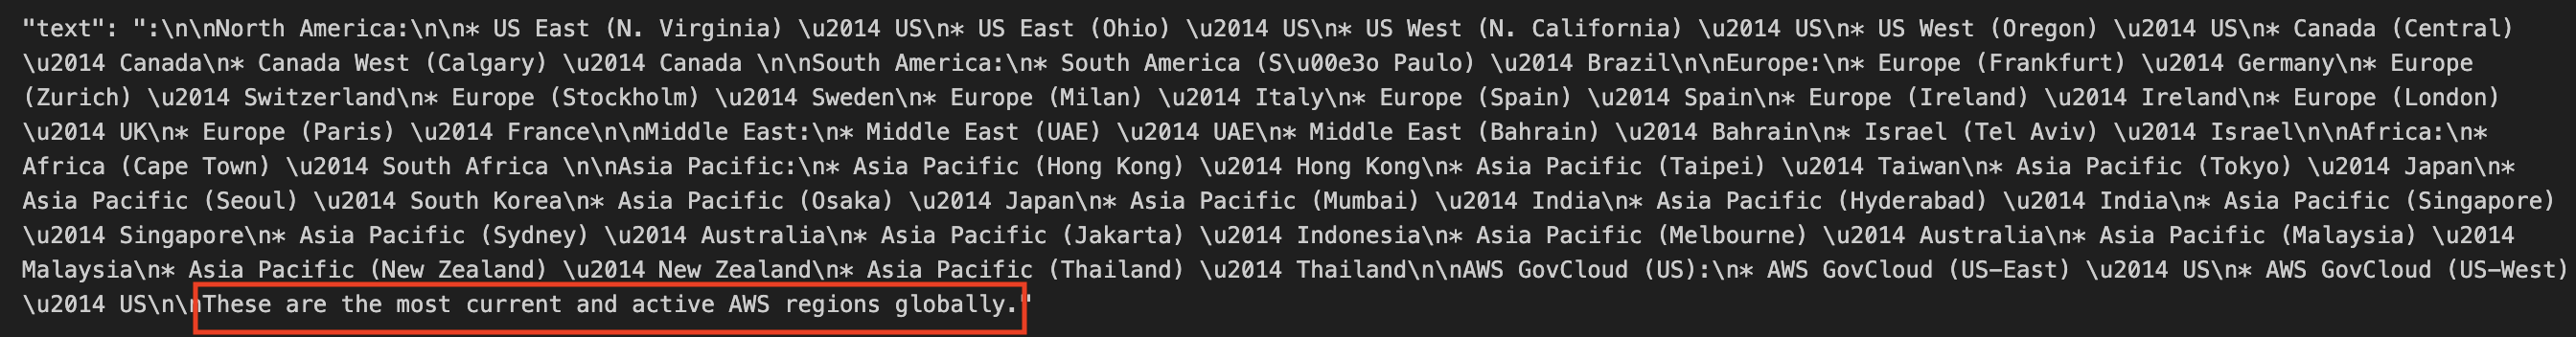
Finally, I can see the list of AWS Regions. It finishes with a message right at the end stating that “These are the most current and active AWS regions globally.”
Web Grounding represents a significant step forward in making AI applications more reliable and current with minimum effort. Whether you’re building customer service chat assistants that need to provide up-to-date accurate information, developing research applications that analyze and synthesize information from multiple sources, or creating travel applications that deliver the latest details about destinations and accommodations, Web Grounding can help you deliver more accurate and relevant responses to your users with a convenient turnkey solution that is straightforward to configure and use.
Things to know Amazon Nova Web Grounding is available today in US East (N. Virginia). Web Grounding will also soon launch on US East (Ohio), and US West (Oregon).
Today, AWS announced that Amazon Kinesis Data Streams now supports record sizes up to 10MiB – a tenfold increase from the previous limit. With this launch, you can now publish intermittent larger data payloads on your data streams while continuing to use existing Kinesis Data Streams APIs in your applications without additional effort. This launch is accompanied by a 2x increase in the maximum PutRecords request size from 5MiB to 10MiB, simplifying data pipelines and reducing operational overhead for IoT analytics, change data capture, and generative AI workloads.
In this post, we explore Amazon Kinesis Data Streams large record support, including key use cases, configuration of maximum record sizes, throttling considerations, and best practices for optimal performance.
Real world use cases
As data volumes grow and use cases evolve, we’ve seen increasing demand for supporting larger record sizes in streaming workloads. Previously, when you needed to process records larger than 1MiB, you had two options:
Split large records into multiple smaller records in producer applications and reassemble them in consumer applications
Both these approaches are useful, but they add complexity to data pipelines, requiring additional code, increasing operational overhead, and complicating error handling and debugging, particularly when customers need to stream large records intermittently.
This enhancement improves the ease of use and reduces operational overhead for customers handling intermittent data payloads across various industries and use cases. In the IoT analytics domain, connected vehicles and industrial equipment are generating increasing volumes of sensor telemetry data, with the size of individual telemetry records occasionally exceeding the previous 1MiB limit in Kinesis. This required customers to implement complex workarounds, such as splitting large records into multiple smaller ones or storing the large records separately and only sending metadata through Kinesis. Similarly, in database change data capture (CDC) pipelines, large transaction records can be produced, especially during bulk operations or schema changes. In the machine learning and generative AI space, workflows are increasingly requiring the ingestion of larger payloads to support richer feature sets and multi-modal data types like audio and images. The increased Kinesis record size limit from 1MiB to 10MiB limits the need for these types of complex workarounds, simplifying data pipelines and reducing operational overhead for customers in IoT, CDC, and advanced analytics use cases. Customers can now more easily ingest and process these intermittent large data records using the same familiar Kinesis APIs.
How it works
To start processing larger records:
Update your stream’s maximum record size limit (maxRecordSize) through the AWS Console, AWS CLI, or AWS SDKs.
Continue using the same PutRecord and PutRecords APIs for producers.
Continue using the same GetRecords or SubscribeToShard APIs for consumers.
Your stream will be in Updating status for a few seconds before being ready to ingest larger records.
Getting started
To start processing larger records with Kinesis Data Streams, you can update the maximum record size by using the AWS Management Console, CLI or SDK.
On the AWS Management Console,
Navigate to the Kinesis Data Streams console.
Choose your stream and select the Configuration tab.
Choose Edit (next to Maximum record size).
Set your desired maximum record size (up to 10MiB).
Save your changes.
Note: This setting only adjusts the maximum record size for this Kinesis data stream. Before increasing this limit, verify that all downstream applications can handle larger records.
Throttling and best practices for optimal performance
Individual shard throughput limits of 1MiB/s for writes and 2MiB/s for reads remain unchanged with support for larger record sizes. To work with large records, let’s understand how throttling works. In a stream, each shard has a throughput capacity of 1 MiB per second. To accommodate large records, each shard temporarily bursts up to 10MiB/s, eventually averaging out to 1MiB per second. To help visualize this behavior, think of each shard having a capacity tank that refills at 1MiB per second. After sending a large record (for example, a 10MiB record), the tank begins refilling immediately, allowing you to send smaller records as capacity becomes available. This capacity to support large records is continuously refilled into the stream. The rate of refilling depends on the size of the large records, the size of the baseline record, the overall traffic pattern, and your chosen partition key strategy. When you process large records, each shard continues to process baseline traffic while leveraging its burst capacity to handle these larger payloads.
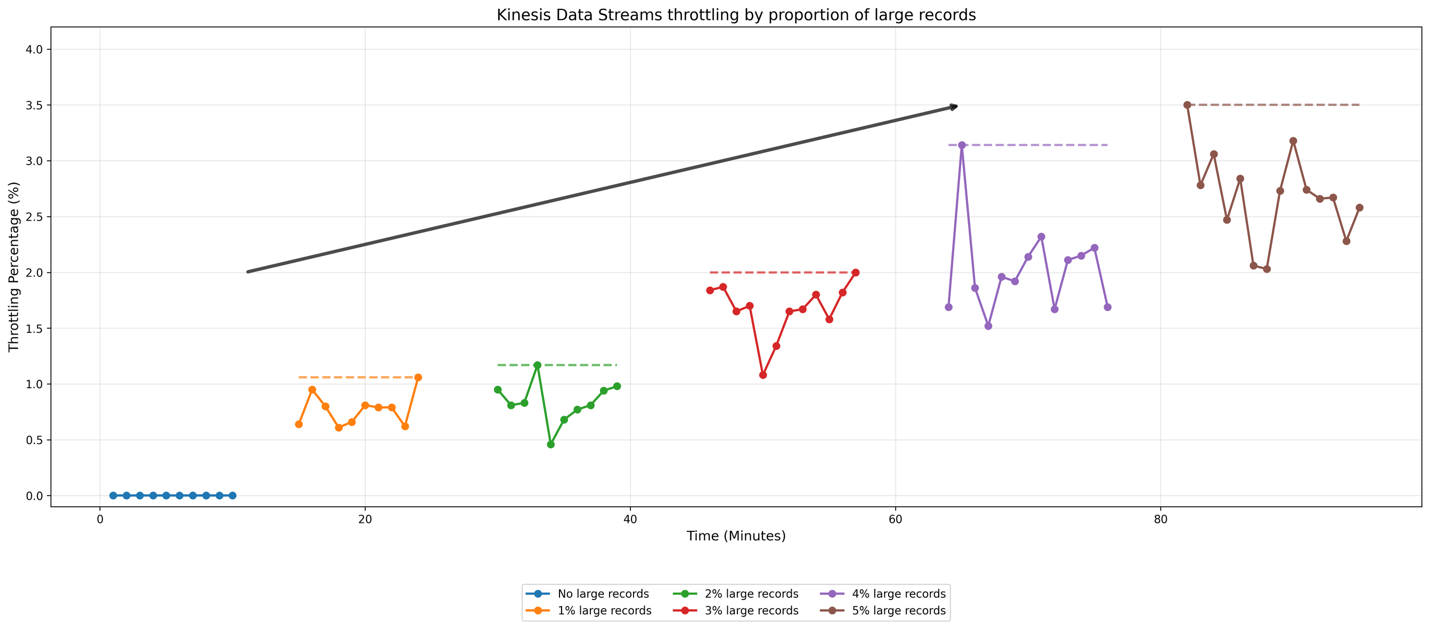
To illustrate how Kinesis Data Streams handles different proportions of large records, let’s examine the results a simple test. For our test configuration, we set up a producer that sends data to an on-demand stream (defaults to 4 shards) at a rate of 50 records per second. The baseline records are 10KiB in size, while large records are 2MiB each. We conducted multiple test cases by progressively increasing the proportion of large records from 1% to 5% of the total stream traffic, along with a baseline case containing no large records. To ensure consistent testing conditions, we distributed the large records uniformly over time for example, in the 1% scenario, we sent one large record for every 100 baseline records. The following graph shows the results:
In the graph, horizontal annotations indicate throttling occurrence peaks. The baseline scenario, represented by the blue line, shows minimal throttling events. As the proportion of large records increases from 1% to 5%, we observe an increase in the rate at which your stream throttles your data, with a notable acceleration in throttling events between the 2% and 5% scenarios. This test demonstrates how Kinesis Data Streams manages increasing proportion of large records.
We recommend maintaining large records at 1-2% of your total record count for optimal performance. In production environments, actual stream behavior varies based on three key factors: the size of baseline records, the size of large records, and the frequency at which large records appear in the stream. We recommend that you test with your demand pattern to determine the specific behavior.
With on-demand streams, when the incoming traffic exceeds 500 KB/s per shard, it splits the shard within 15 minutes. The parent shard’s hash key values are redistributed evenly across child shards. Kinesis automatically scales the stream to increase the number of shards, enabling distribution of large records across a larger number of shards depending on the partition key strategy employed.
For optimal performance with large records:
Use a random partition key strategy to distribute large records evenly across shards.
Implement backoff and retry logic in producer applications.
Monitor shard-level metrics to identify potential bottlenecks.
If you still need to continuously stream of large records, consider using Amazon S3 to store payloads and send only metadata references to the stream. Refer to Processing large records with Amazon Kinesis Data Streams for more information.
Conclusion
Amazon Kinesis Data Streams now supports record sizes up to 10MiB, a tenfold increase from the previous 1MiB limit. This enhancement simplifies data pipelines for IoT analytics, change data capture, and AI/ML workloads by eliminating the need for complex workarounds. You can continue using existing Kinesis Data Streams APIs without additional code changes and benefit from increased flexibility in handling intermittent large payloads.
For optimal performance, we recommend maintaining large records at 1-2% of total record count.
For best results with large records, implement a uniformly distributed partition key strategy to evenly distribute records across shards, include backoff and retry logic in producer applications, and monitor shard-level metrics to identify potential bottlenecks.
Before increasing the maximum record size, verify that all downstream applications and consumers can handle larger records.
We’re excited to see how you’ll leverage this capability to build more powerful and efficient streaming applications. To learn more, visit the Amazon Kinesis Data Streams documentation.
Site reliability engineers (SREs) are measured by one thing above all: keeping systems available when it matters most. They’re the ones getting calls at midnight, managing the war room during outages, and preventing small hiccups from snowballing into customer-facing failures.
But storage from major cloud providers often makes their job harder. Tiering delays stretch out recovery times. Replication gaps create blind spots across regions. Complex policy chains flood monitoring systems with noise. Instead of protecting reliability, general-purpose storage often undermines it.
What SREs need is a storage layer that works with them, not against them—one that delivers durability without complexity, speed without cold-tier delays, and clarity without policy sprawl.
A specialized, always-hot storage foundation provides exactly that.
This is the final post in our three-part series on how specialized storage helps every member of a cloud-native team. (See articles one and two to get the full story.) This time, we’re zeroing in on the reliability engineers who keep customer-facing systems humming behind the scenes.
Build a disaster recovery plan that’s ready for anything
For SREs, storage is the backbone of availability and recovery. When it falters, the blast radius spreads fast. Even a minor failure can ripple outward and amplify the impact of every incident.
In the sections below, we’ll look at how those ripple effects play out in real-world scenarios, and how specialized, always-hot storage helps SREs contain failures, recover faster, and quiet the noise that makes reliability so hard to sustain.
Contain the blast radius
SREs spend much of their time running “what-if” drills. What if a drive fails? What if a region goes down? What if replication lags behind?
With general-purpose cloud storage, those “what-ifs” become real risks:
Tiering delays: Infrequently accessed data is automatically pushed into colder, slower tiers. During an incident, archived data such as logs or snapshots must be restored before it’s usable. This slows recovery when seconds count.
Replication gaps: Replication isn’t always immediate or consistent across regions. When writes lag or copies fall out of sync, recovery data can be stale or incomplete, leaving teams guessing at the true state of their systems.
Policy complexity: Layers of identity and access management (IAM), lifecycle, and routing policies often overlap in unpredictable ways. A single misconfiguration—like archiving active data or blocking a needed API—can cascade through dependent services, turning a minor error into a wider outage.
Each layer meant to increase flexibility instead adds fragility.
Specialized storage changes that dynamic. Designed for worry-free durability and built to eliminate single points of failure, it distributes data across independent systems so localized issues don’t cascade. Even if hardware fails or a region experiences disruption, data remains accessible and recovery stays predictable. For SREs, that means fewer nightmare scenarios to model, fewer “what-ifs” in runbooks, and faster, more confident recovery.
Cut mean time to recovery (MTTR), protect SLAs
When an incident hits, the SLA clock starts ticking. Every minute spent waiting on logs, snapshots, or configs adds pressure from customers and leadership alike.
But in tiered storage systems, those critical assets are often parked in colder, low-cost tiers meant for archival access rather than fast recovery. Pulling them back can take hours or even days before triage can begin. That latency bloats MTTR and turns manageable events into prolonged outages with real customer impact.
Specialized storage eliminates these bottlenecks. Always-hot data and millisecond reads give SREs immediate visibility into logs, snapshots, and configs, so evidence is available the moment an incident begins. Instead of stalling while waiting on a restore job, teams can dive directly into diagnosis and resolution. The results are faster MTTR, steadier SLA performance, and fewer fire drills turning into headline outages.
Reduce alert fatigue
Ask any SRE what wears them down and the answer comes quickly: false alarms and 3 a.m. wake-ups. The incident itself may be rare, but the noise leading up to it is relentless.
In big-cloud environments, complexity breeds that noise:
Lifecycle policies silently archive data until a request fails
IAM rules misalign with pipeline needs
Tier transitions or throttling events masquerade as outages in monitoring dashboards.
Each quirk becomes another alert, another call, another night interrupted. Over time, the noise blends with the signal, and teams start second-guessing what’s real. Alert fatigue sets in. Engineers tune out notifications or delay responses, not from neglect but from exhaustion. The result is a slower reaction when a real outage hits, which is exactly the scenario the alerts were meant to prevent.
Specialized storage dials down the chaos. A single-tier design with clear access controls strips away layers of risk, keeping alerts meaningful and edge cases rare. Instead of burning cycles firefighting brittle rules, SREs can focus on resilience engineering and prevent outages in the first place.
Rethink storage, strengthen reliability
The SRE role is already demanding. Storage shouldn’t add to the burden. An always-hot storage layer gives teams the durability, speed, and simplicity they need to keep systems reliable without extra toil.
Backblaze B2 was built with SREs in mind:
Architected for 11 nine’s of durability
Millisecond reads that slash MTTR and protect SLAs.
Simplified architecture that cuts noise and pager fatigue.
You don’t need to rebuild your stack to get these benefits. Just swap the endpoint and redeploy. With Backblaze B2, storage stops undermining reliability and starts strengthening it.
Tired of midnight pages for preventable storage issues? There’s a better way. Explore how Backblaze B2 fits into your reliability workflows, and how much calmer on-call life feels when storage simply works.
Fil-C is a memory-safe implementation of C and C++ that aims to let C code —
complete with pointer arithmetic, unions, and other features that are often
cited as a problem for memory-safe languages — run safely, unmodified.
Its dedication to being “fanatically
compatible” makes it an attractive choice for retrofitting memory-safety
into existing applications. Despite the project’s relative youth and single
active contributor, Fil-C is capable of compiling an
entire memory-safe Linux user space (based on
Linux From Scratch),
albeit with some modifications to the more complex programs. It also features
memory-safe signal handling and a concurrent garbage collector.
I am delighted to announce that the Raspberry Pi Foundation is the new home for Blockly, the world’s leading open source library for visual programming.
What is Blockly?
Blockly is a free, open source library that enables developers to build applications and websites that use block-based coding interfaces. That means that instead of typing code, you snap blocks together to build programs. Behind the scenes, those blocks are turned into text-based code like JavaScript and Python.
Blockly started life in 2011 in Google as a passion project of one engineer. Since then — thanks to the generous support of Google, a small team of brilliant engineers, and an amazing community of open source contributors and partners — it has grown to become the de facto standard for visual programming interfaces.
In particular, Blockly is the foundation for pretty much all of the block-based coding applications that you may have used to teach or learn about programming. Platforms like Scratch, MakeCode, and MIT’s App Inventor are all built with Blockly. It’s no exaggeration to say that hundreds of millions of young people have learnt the fundamentals of computer science using software that is built with Blockly.
As we enter the age of AI, it is more important than ever that all young people develop a foundational understanding of computer science. Blockly and the block-based coding platforms and applications that it enables are essential to realising that vision.
You can read more about the importance of coding in the age of AI in our position paper.
Blockly is also widely used to create interfaces that control hardware and robotics platforms. And, while its main use cases are in education, Blockly is increasingly being used to build industrial and commercial applications.
What does this change mean?
From 10 November 2025, the Blockly open source library and assets, and key members of the Blockly team will transition from Google to the Raspberry Pi Foundation.
Our vision is for Blockly to continue to be the standard visual programming interface that makes coding accessible to all. We are committed to maintaining Blockly as an open source project, and to working collaboratively with the community of developers and educators.
Over the next year, we will roll out features that improve accessibility, including screen reader support and keyboard navigation, working closely with partners to support implementation of these accessibility improvements across their platforms.
Looking to the future, we want to make sure that Blockly is at the leading edge of innovations that support the teaching and learning of programming in the age of AI. We’re also excited about the potential for the Blockly team to collaborate with the Foundation’s research, learning, and product teams.
If you are already part of the community of developers and educators, then I want to reassure you that you can continue to expect the same outstanding partnership and support from the Blockly team. We also look forward to welcoming many more members to the Blockly community over the coming years.
Finally, I want to say a huge thank you to Google for their support for Blockly over the years, and for enabling this transition with generous grant funding.
Today, we’re introducing Amazon Nova Multimodal Embeddings, a state-of-the-art multimodal embedding model for agentic retrieval-augmented generation (RAG) and semantic search applications, available in Amazon Bedrock. It is the first unified embedding model that supports text, documents, images, video, and audio through a single model to enable crossmodal retrieval with leading accuracy.
Embedding models convert textual, visual, and audio inputs into numerical representations called embeddings. These embeddings capture the meaning of the input in a way that AI systems can compare, search, and analyze, powering use cases such as semantic search and RAG.
Organizations are increasingly seeking solutions to unlock insights from the growing volume of unstructured data that is spread across text, image, document, video, and audio content. For example, an organization might have product images, brochures that contain infographics and text, and user-uploaded video clips. Embedding models are able to unlock value from unstructured data, however traditional models are typically specialized to handle one content type. This limitation drives customers to either build complex crossmodal embedding solutions or restrict themselves to use cases focused on a single content type. The problem also applies to mixed-modality content types such as documents with interleaved text and images or video with visual, audio, and textual elements where existing models struggle to capture crossmodal relationships effectively.
Nova Multimodal Embeddings supports a unified semantic space for text, documents, images, video, and audio for use cases such as crossmodal search across mixed-modality content, searching with a reference image, and retrieving visual documents.
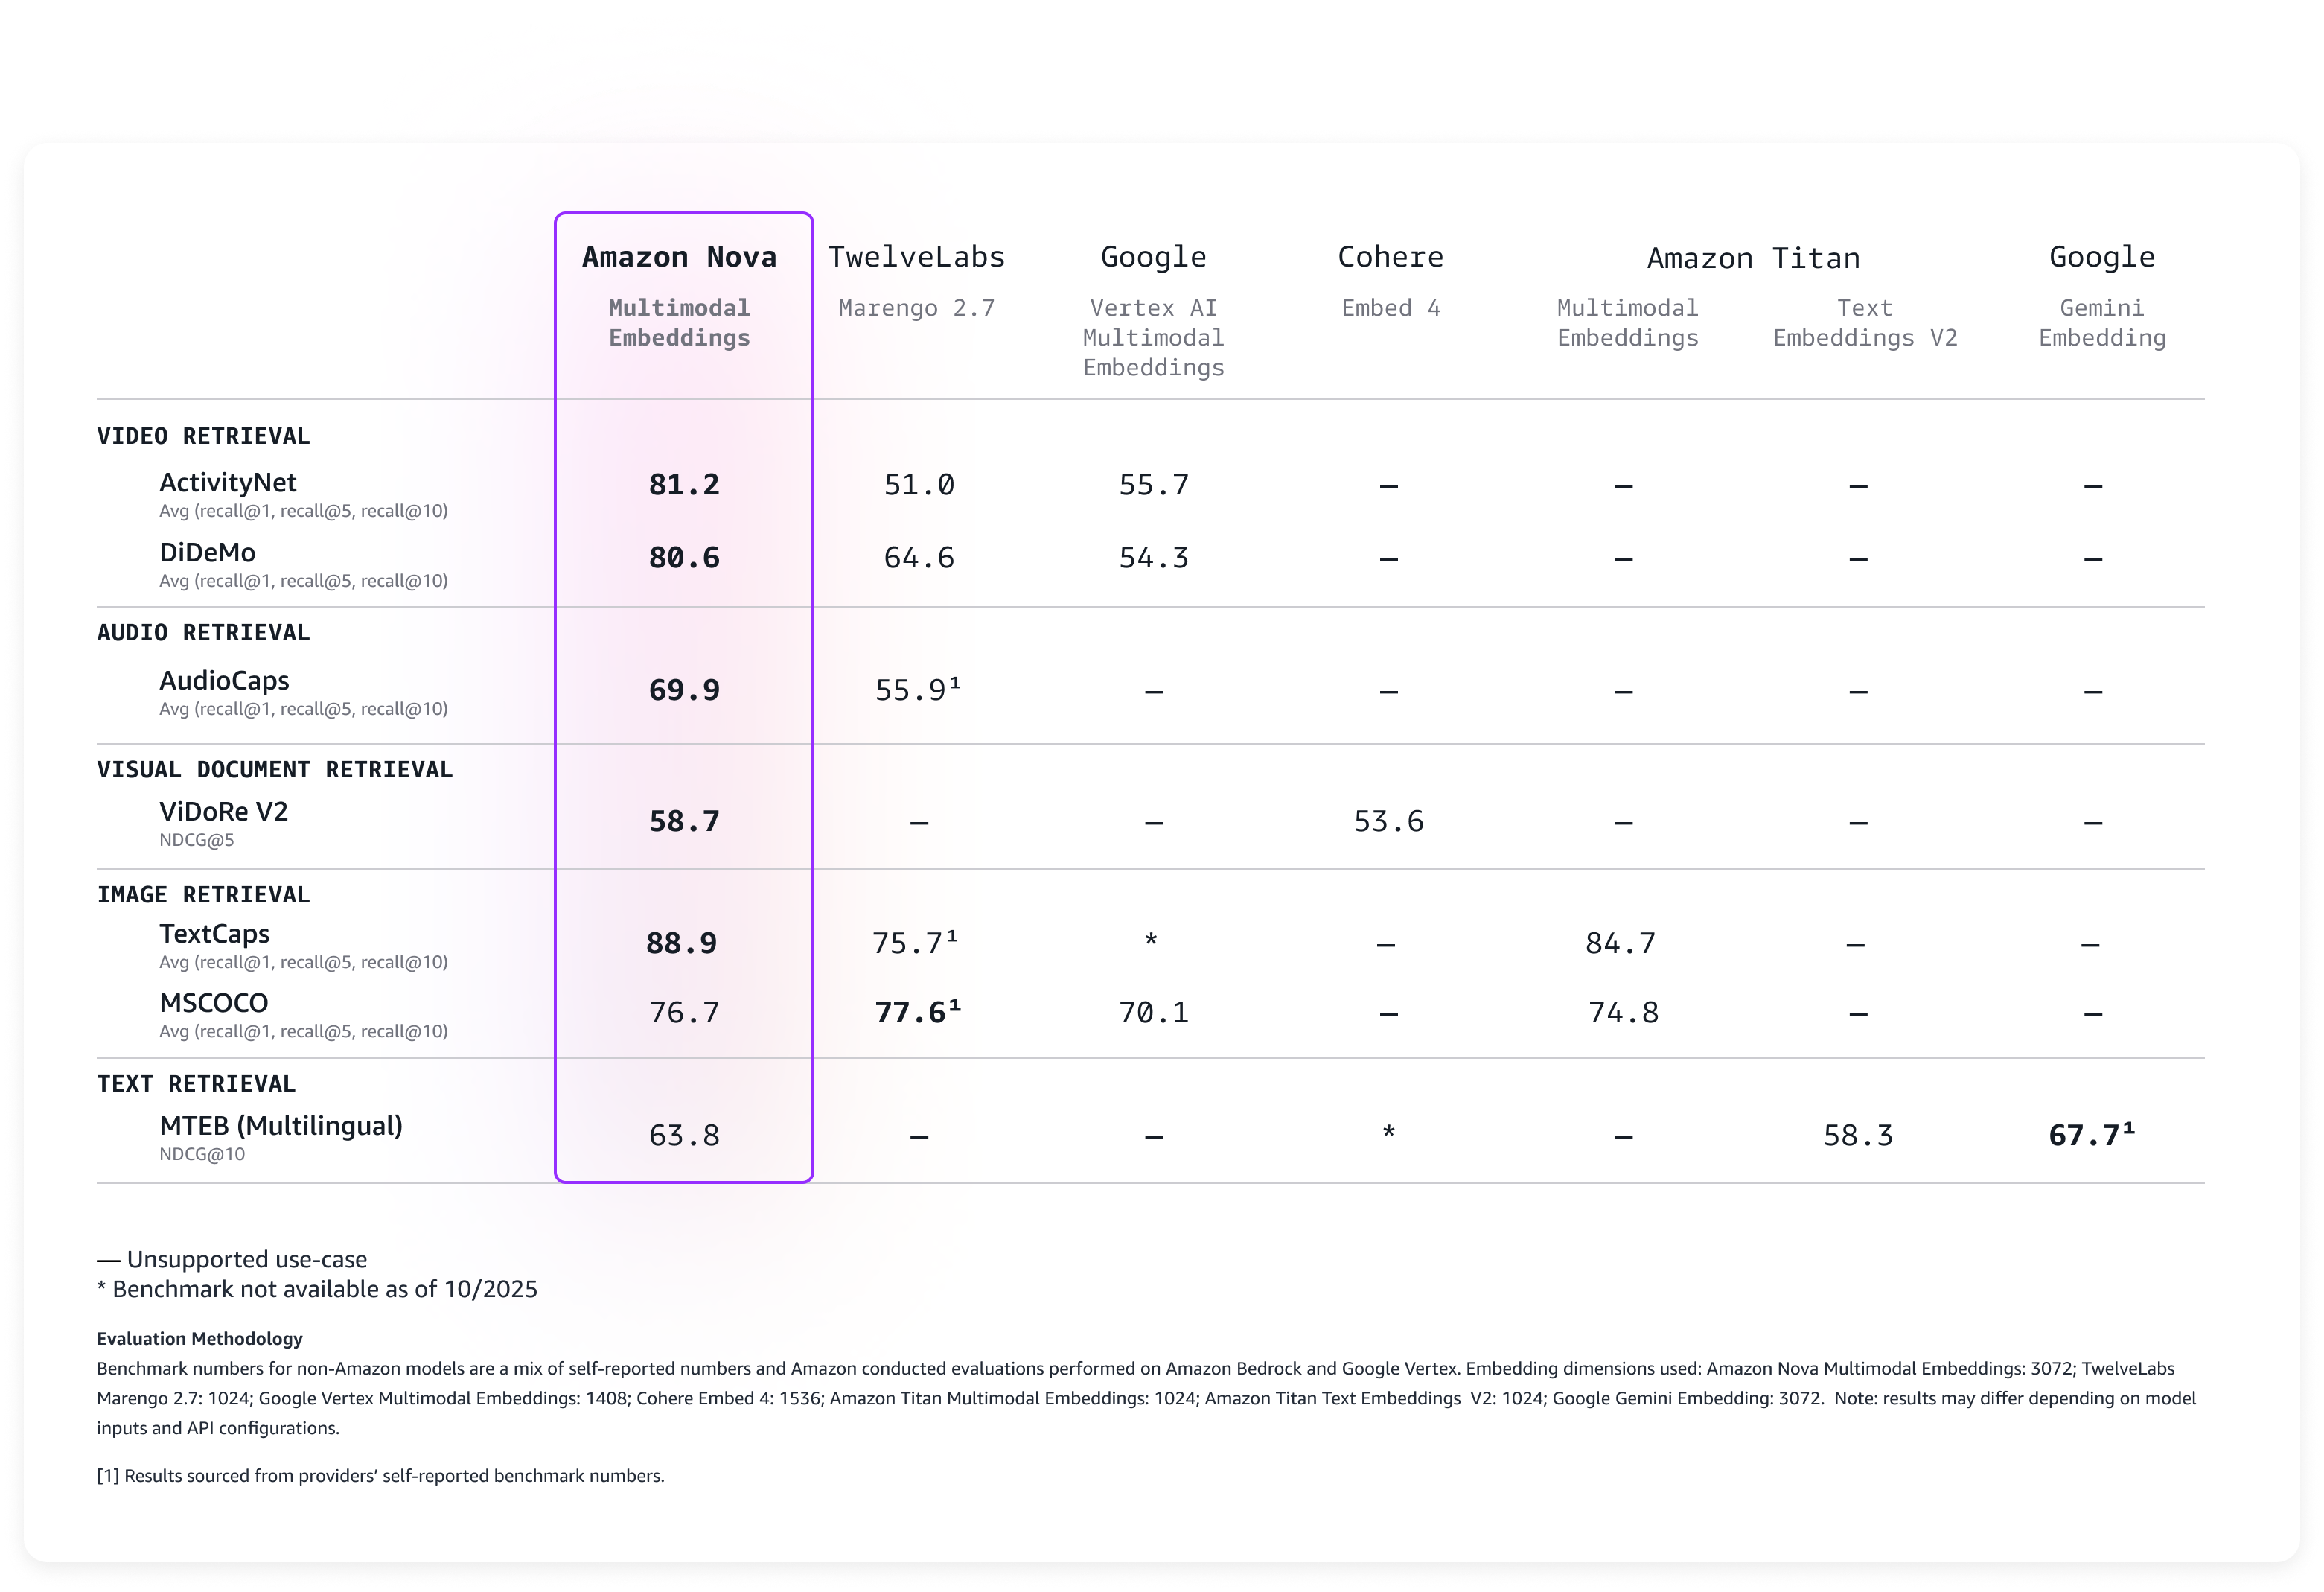
Evaluating Amazon Nova Multimodal Embeddings performance We evaluated the model on a broad range of benchmarks, and it delivers leading accuracy out-of-the-box as described in the following table.
Nova Multimodal Embeddings supports a context length of up to 8K tokens, text in up to 200 languages, and accepts inputs via synchronous and asynchronous APIs. Additionally, it supports segmentation (also known as “chunking”) to partition long-form text, video, or audio content into manageable segments, generating embeddings for each portion. Lastly, the model offers four output embedding dimensions, trained using Matryoshka Representation Learning (MRL) that enables low-latency end-to-end retrieval with minimal accuracy changes.
Let’s see how the new model can be used in practice.
Using Amazon Nova Multimodal Embeddings Getting started with Nova Multimodal Embeddings follows the same pattern as other models in Amazon Bedrock. The model accepts text, documents, images, video, or audio as input and returns numerical embeddings that you can use for semantic search, similarity comparison, or RAG.
Here’s a practical example using the AWS SDK for Python (Boto3) that shows how to create embeddings from different content types and store them for later retrieval. For simplicity, I’ll use Amazon S3 Vectors, a cost-optimized storage with native support for storing and querying vectors at any scale, to store and search the embeddings.
Let’s start with the fundamentals: converting text into embeddings. This example shows how to transform a simple text description into a numerical representation that captures its semantic meaning. These embeddings can later be compared with embeddings from documents, images, videos, or audio to find related content.
To make the code easy to follow, I’ll show a section of the script at a time. The full script is included at the end of this walkthrough.
import json
import base64
import time
import boto3

MODEL_ID = "amazon.nova-2-multimodal-embeddings-v1:0"
EMBEDDING_DIMENSION = 3072

# Initialize Amazon Bedrock Runtime client
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

print(f"Generating text embedding with {MODEL_ID} ...")

# Text to embed
text = "Amazon Nova is a multimodal foundation model"

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "text": {"truncationMode": "END", "value": text},
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")
Now we’ll process visual content using the same embedding space using a photo.jpg file in the same folder as the script. This demonstrates the power of multimodality: Nova Multimodal Embeddings is able to capture both textual and visual context into a single embedding that provides enhanced understanding of the document.
Nova Multimodal Embeddings can generate embeddings that are optimized for how they are being used. When indexing for a search or retrieval use case, embeddingPurpose can be set to GENERIC_INDEX. For the query step, embeddingPurpose can be set depending on the type of item to be retrieved. For example, when retrieving documents, embeddingPurpose can be set to DOCUMENT_RETRIEVAL.
To process video content, I use the asynchronous API. That’s a requirement for videos that are larger than 25MB when encoded as Base64. First, I upload a local video to an S3 bucket in the same AWS Region.
This example shows how to extract embeddings from both visual and audio components of a video file. The segmentation feature breaks longer videos into manageable chunks, making it practical to search through hours of content efficiently.
# Initialize Amazon S3 client
s3 = boto3.client("s3", region_name="us-east-1")
print(f"Generating video embedding with {MODEL_ID} ...")
# Amazon S3 URIs
S3_VIDEO_URI = "s3://my-video-bucket/videos/presentation.mp4"
S3_EMBEDDING_DESTINATION_URI = "s3://my-embedding-destination-bucket/embeddings-output/"
# Create async embedding job for video with audio
model_input = {
"taskType": "SEGMENTED_EMBEDDING",
"segmentedEmbeddingParams": {
"embeddingPurpose": "GENERIC_INDEX",
"embeddingDimension": EMBEDDING_DIMENSION,
"video": {
"format": "mp4",
"embeddingMode": "AUDIO_VIDEO_COMBINED",
"source": {
"s3Location": {"uri": S3_VIDEO_URI}
},
"segmentationConfig": {
"durationSeconds": 15 # Segment into 15-second chunks
},
},
},
}
response = bedrock_runtime.start_async_invoke(
modelId=MODEL_ID,
modelInput=model_input,
outputDataConfig={
"s3OutputDataConfig": {
"s3Uri": S3_EMBEDDING_DESTINATION_URI
}
},
)
invocation_arn = response["invocationArn"]
print(f"Async job started: {invocation_arn}")
# Poll until job completes
print("\nPolling for job completion...")
while True:
job = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
status = job["status"]
print(f"Status: {status}")
if status != "InProgress":
break
time.sleep(15)
# Check if job completed successfully
if status == "Completed":
output_s3_uri = job["outputDataConfig"]["s3OutputDataConfig"]["s3Uri"]
print(f"\nSuccess! Embeddings at: {output_s3_uri}")
# Parse S3 URI to get bucket and prefix
s3_uri_parts = output_s3_uri[5:].split("/", 1) # Remove "s3://" prefix
bucket = s3_uri_parts[0]
prefix = s3_uri_parts[1] if len(s3_uri_parts) > 1 else ""
# AUDIO_VIDEO_COMBINED mode outputs to embedding-audio-video.jsonl
# The output_s3_uri already includes the job ID, so just append the filename
embeddings_key = f"{prefix}/embedding-audio-video.jsonl".lstrip("/")
print(f"Reading embeddings from: s3://{bucket}/{embeddings_key}")
# Read and parse JSONL file
response = s3.get_object(Bucket=bucket, Key=embeddings_key)
content = response['Body'].read().decode('utf-8')
embeddings = []
for line in content.strip().split('\n'):
if line:
embeddings.append(json.loads(line))
print(f"\nFound {len(embeddings)} video segments:")
for i, segment in enumerate(embeddings):
print(f" Segment {i}: {segment.get('startTime', 0):.1f}s - {segment.get('endTime', 0):.1f}s")
print(f" Embedding dimension: {len(segment.get('embedding', []))}")
else:
print(f"\nJob failed: {job.get('failureMessage', 'Unknown error')}")
With our embeddings generated, we need a place to store and search them efficiently. This example demonstrates setting up a vector store using Amazon S3 Vectors, which provides the infrastructure needed for similarity search at scale. Think of this as creating a searchable index where semantically similar content naturally clusters together. When adding an embedding to the index, I use the metadata to specify the original format and the content being indexed.
# Initialize Amazon S3 Vectors client
s3vectors = boto3.client("s3vectors", region_name="us-east-1")
# Configuration
VECTOR_BUCKET = "my-vector-store"
INDEX_NAME = "embeddings"
# Create vector bucket and index (if they don't exist)
try:
s3vectors.get_vector_bucket(vectorBucketName=VECTOR_BUCKET)
print(f"Vector bucket {VECTOR_BUCKET} already exists")
except s3vectors.exceptions.NotFoundException:
s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)
print(f"Created vector bucket: {VECTOR_BUCKET}")
try:
s3vectors.get_index(vectorBucketName=VECTOR_BUCKET, indexName=INDEX_NAME)
print(f"Vector index {INDEX_NAME} already exists")
except s3vectors.exceptions.NotFoundException:
s3vectors.create_index(
vectorBucketName=VECTOR_BUCKET,
indexName=INDEX_NAME,
dimension=EMBEDDING_DIMENSION,
dataType="float32",
distanceMetric="cosine"
)
print(f"Created index: {INDEX_NAME}")
texts = [
"Machine learning on AWS",
"Amazon Bedrock provides foundation models",
"S3 Vectors enables semantic search"
]
print(f"\nGenerating embeddings for {len(texts)} texts...")
# Generate embeddings using Amazon Nova for each text
vectors = []
for text in texts:
response = bedrock_runtime.invoke_model(
body=json.dumps({
"taskType": "SINGLE_EMBEDDING",
"singleEmbeddingParams": {
"embeddingDimension": EMBEDDING_DIMENSION,
"text": {"truncationMode": "END", "value": text}
}
}),
modelId=MODEL_ID,
accept="application/json",
contentType="application/json"
)
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]
vectors.append({
"key": f"text:{text[:50]}", # Unique identifier
"data": {"float32": embedding},
"metadata": {"type": "text", "content": text}
})
print(f" ✓ Generated embedding for: {text}")
# Add all vectors to store in a single call
s3vectors.put_vectors(
vectorBucketName=VECTOR_BUCKET,
indexName=INDEX_NAME,
vectors=vectors
)
print(f"\nSuccessfully added {len(vectors)} vectors to the store in one put_vectors call!")
This final example demonstrates the capability of searching across different content types with a single query, finding the most similar content regardless of whether it originated from text, images, videos, or audio. The distance scores help you understand how closely related the results are to your original query.
# Text to query
query_text = "foundation models"
print(f"\nGenerating embeddings for query '{query_text}' ...")
# Generate embeddings
response = bedrock_runtime.invoke_model(
body=json.dumps({
"taskType": "SINGLE_EMBEDDING",
"singleEmbeddingParams": {
"embeddingPurpose": "GENERIC_RETRIEVAL",
"embeddingDimension": EMBEDDING_DIMENSION,
"text": {"truncationMode": "END", "value": query_text}
}
}),
modelId=MODEL_ID,
accept="application/json",
contentType="application/json"
)
response_body = json.loads(response["body"].read())
query_embedding = response_body["embeddings"][0]["embedding"]
print(f"Searching for similar embeddings...\n")
# Search for top 5 most similar vectors
response = s3vectors.query_vectors(
vectorBucketName=VECTOR_BUCKET,
indexName=INDEX_NAME,
queryVector={"float32": query_embedding},
topK=5,
returnDistance=True,
returnMetadata=True
)
# Display results
print(f"Found {len(response['vectors'])} results:\n")
for i, result in enumerate(response["vectors"], 1):
print(f"{i}. {result['key']}")
print(f" Distance: {result['distance']:.4f}")
if result.get("metadata"):
print(f" Metadata: {result['metadata']}")
print()
Crossmodal search is one of the key advantages of multimodal embeddings. With crossmodal search, you can query with text and find relevant images. You can also search for videos using text descriptions, find audio clips that match certain topics, or discover documents based on their visual and textual content. For your reference, the full script with all previous examples merged together is here:
import json
import base64
import time
import boto3
MODEL_ID = "amazon.nova-2-multimodal-embeddings-v1:0"
EMBEDDING_DIMENSION = 3072
# Initialize Amazon Bedrock Runtime client
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")
print(f"Generating text embedding with {MODEL_ID} ...")
# Text to embed
text = "Amazon Nova is a multimodal foundation model"
# Create embedding
request_body = {
"taskType": "SINGLE_EMBEDDING",
"singleEmbeddingParams": {
"embeddingPurpose": "GENERIC_INDEX",
"embeddingDimension": EMBEDDING_DIMENSION,
"text": {"truncationMode": "END", "value": text},
},
}
response = bedrock_runtime.invoke_model(
body=json.dumps(request_body),
modelId=MODEL_ID,
contentType="application/json",
)
# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]
print(f"Generated embedding with {len(embedding)} dimensions")
# Read and encode image
print(f"Generating image embedding with {MODEL_ID} ...")

with open("photo.jpg", "rb") as f:
    image_bytes = base64.b64encode(f.read()).decode("utf-8")

# Create embedding
request_body = {
    "taskType": "SINGLE_EMBEDDING",
    "singleEmbeddingParams": {
        "embeddingPurpose": "GENERIC_INDEX",
        "embeddingDimension": EMBEDDING_DIMENSION,
        "image": {
            "format": "jpeg",
            "source": {"bytes": image_bytes}
        },
    },
}

response = bedrock_runtime.invoke_model(
    body=json.dumps(request_body),
    modelId=MODEL_ID,
    contentType="application/json",
)

# Extract embedding
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]

print(f"Generated embedding with {len(embedding)} dimensions")
# Initialize Amazon S3 client
s3 = boto3.client("s3", region_name="us-east-1")
print(f"Generating video embedding with {MODEL_ID} ...")
# Amazon S3 URIs
S3_VIDEO_URI = "s3://my-video-bucket/videos/presentation.mp4"
# Amazon S3 output bucket and location
S3_EMBEDDING_DESTINATION_URI = "s3://my-video-bucket/embeddings-output/"
# Create async embedding job for video with audio
model_input = {
"taskType": "SEGMENTED_EMBEDDING",
"segmentedEmbeddingParams": {
"embeddingPurpose": "GENERIC_INDEX",
"embeddingDimension": EMBEDDING_DIMENSION,
"video": {
"format": "mp4",
"embeddingMode": "AUDIO_VIDEO_COMBINED",
"source": {
"s3Location": {"uri": S3_VIDEO_URI}
},
"segmentationConfig": {
"durationSeconds": 15 # Segment into 15-second chunks
},
},
},
}
response = bedrock_runtime.start_async_invoke(
modelId=MODEL_ID,
modelInput=model_input,
outputDataConfig={
"s3OutputDataConfig": {
"s3Uri": S3_EMBEDDING_DESTINATION_URI
}
},
)
invocation_arn = response["invocationArn"]
print(f"Async job started: {invocation_arn}")
# Poll until job completes
print("\nPolling for job completion...")
while True:
job = bedrock_runtime.get_async_invoke(invocationArn=invocation_arn)
status = job["status"]
print(f"Status: {status}")
if status != "InProgress":
break
time.sleep(15)
# Check if job completed successfully
if status == "Completed":
output_s3_uri = job["outputDataConfig"]["s3OutputDataConfig"]["s3Uri"]
print(f"\nSuccess! Embeddings at: {output_s3_uri}")
# Parse S3 URI to get bucket and prefix
s3_uri_parts = output_s3_uri[5:].split("/", 1) # Remove "s3://" prefix
bucket = s3_uri_parts[0]
prefix = s3_uri_parts[1] if len(s3_uri_parts) > 1 else ""
# AUDIO_VIDEO_COMBINED mode outputs to embedding-audio-video.jsonl
# The output_s3_uri already includes the job ID, so just append the filename
embeddings_key = f"{prefix}/embedding-audio-video.jsonl".lstrip("/")
print(f"Reading embeddings from: s3://{bucket}/{embeddings_key}")
# Read and parse JSONL file
response = s3.get_object(Bucket=bucket, Key=embeddings_key)
content = response['Body'].read().decode('utf-8')
embeddings = []
for line in content.strip().split('\n'):
if line:
embeddings.append(json.loads(line))
print(f"\nFound {len(embeddings)} video segments:")
for i, segment in enumerate(embeddings):
print(f" Segment {i}: {segment.get('startTime', 0):.1f}s - {segment.get('endTime', 0):.1f}s")
print(f" Embedding dimension: {len(segment.get('embedding', []))}")
else:
print(f"\nJob failed: {job.get('failureMessage', 'Unknown error')}")
# Initialize Amazon S3 Vectors client
s3vectors = boto3.client("s3vectors", region_name="us-east-1")
# Configuration
VECTOR_BUCKET = "my-vector-store"
INDEX_NAME = "embeddings"
# Create vector bucket and index (if they don't exist)
try:
s3vectors.get_vector_bucket(vectorBucketName=VECTOR_BUCKET)
print(f"Vector bucket {VECTOR_BUCKET} already exists")
except s3vectors.exceptions.NotFoundException:
s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)
print(f"Created vector bucket: {VECTOR_BUCKET}")
try:
s3vectors.get_index(vectorBucketName=VECTOR_BUCKET, indexName=INDEX_NAME)
print(f"Vector index {INDEX_NAME} already exists")
except s3vectors.exceptions.NotFoundException:
s3vectors.create_index(
vectorBucketName=VECTOR_BUCKET,
indexName=INDEX_NAME,
dimension=EMBEDDING_DIMENSION,
dataType="float32",
distanceMetric="cosine"
)
print(f"Created index: {INDEX_NAME}")
texts = [
"Machine learning on AWS",
"Amazon Bedrock provides foundation models",
"S3 Vectors enables semantic search"
]
print(f"\nGenerating embeddings for {len(texts)} texts...")
# Generate embeddings using Amazon Nova for each text
vectors = []
for text in texts:
response = bedrock_runtime.invoke_model(
body=json.dumps({
"taskType": "SINGLE_EMBEDDING",
"singleEmbeddingParams": {
"embeddingPurpose": "GENERIC_INDEX",
"embeddingDimension": EMBEDDING_DIMENSION,
"text": {"truncationMode": "END", "value": text}
}
}),
modelId=MODEL_ID,
accept="application/json",
contentType="application/json"
)
response_body = json.loads(response["body"].read())
embedding = response_body["embeddings"][0]["embedding"]
vectors.append({
"key": f"text:{text[:50]}", # Unique identifier
"data": {"float32": embedding},
"metadata": {"type": "text", "content": text}
})
print(f" ✓ Generated embedding for: {text}")
# Add all vectors to store in a single call
s3vectors.put_vectors(
vectorBucketName=VECTOR_BUCKET,
indexName=INDEX_NAME,
vectors=vectors
)
print(f"\nSuccessfully added {len(vectors)} vectors to the store in one put_vectors call!")
# Text to query
query_text = "foundation models"

print(f"\nGenerating embeddings for query '{query_text}' ...")

# Generate embeddings
response = bedrock_runtime.invoke_model(
    body=json.dumps({
        "taskType": "SINGLE_EMBEDDING",
        "singleEmbeddingParams": {
            "embeddingPurpose": "GENERIC_RETRIEVAL",
            "embeddingDimension": EMBEDDING_DIMENSION,
            "text": {"truncationMode": "END", "value": query_text}
        }
    }),
    modelId=MODEL_ID,
    accept="application/json",
    contentType="application/json"
)

response_body = json.loads(response["body"].read())
query_embedding = response_body["embeddings"][0]["embedding"]

print(f"Searching for similar embeddings...\n")

# Search for top 5 most similar vectors
response = s3vectors.query_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    queryVector={"float32": query_embedding},
    topK=5,
    returnDistance=True,
    returnMetadata=True
)

# Display results
print(f"Found {len(response['vectors'])} results:\n")
for i, result in enumerate(response["vectors"], 1):
    print(f"{i}. {result['key']}")
    print(f"   Distance: {result['distance']:.4f}")
    if result.get("metadata"):
        print(f"   Metadata: {result['metadata']}")
    print()
For production applications, embeddings can be stored in any vector database. Amazon OpenSearch Service offers native integration with Nova Multimodal Embeddings at launch, making it straightforward to build scalable search applications. As shown in the examples before, Amazon S3 Vectors provides a simple way to store and query embeddings with your application data.
Things to know Nova Multimodal Embeddings offers four output dimension options: 3,072, 1,024, 384, and 256. Larger dimensions provide more detailed representations but require more storage and computation. Smaller dimensions offer a practical balance between retrieval performance and resource efficiency. This flexibility helps you optimize for your specific application and cost requirements.
The model handles substantial context lengths. For text inputs, it can process up to 8,192 tokens at once. Video and audio inputs support segments of up to 30 seconds, and the model can segment longer files. This segmentation capability is particularly useful when working with large media files—the model splits them into manageable pieces and creates embeddings for each segment.
The model includes responsible AI features built into Amazon Bedrock. Content submitted for embedding goes through Amazon Bedrock content safety filters, and the model includes fairness measures to reduce bias.
As described in the code examples, the model can be invoked through both synchronous and asynchronous APIs. The synchronous API works well for real-time applications where you need immediate responses, such as processing user queries in a search interface. The asynchronous API handles latency insensitive workloads more efficiently, making it suitable for processing large content such as videos.
If you’re using an AI–powered assistant for software development such as Amazon Q Developer or Kiro, you can set up the AWS API MCP Server to help the AI assistants interact with AWS services and resources and the AWS Knowledge MCP Server to provide up-to-date documentation, code samples, knowledge about the regional availability of AWS APIs and CloudFormation resources.
Start building multimodal AI-powered applications with Nova Multimodal Embeddings today, and share your feedback through AWS re:Post for Amazon Bedrock or your usual AWS Support contacts.
For those of you installing fresh Fedora Linux 43 Spins, you may be
greeted with the new Anaconda WebUI. This was the default installer
interface for Fedora Workstation 42, and now it’s the default
installer UI for the Spins as well.
If you are a GNOME desktop user, you’ll also notice that the GNOME
is now Wayland-only in Fedora Linux 43. GNOME upstream has deprecated
X11 support, and has disabled it as a compile time default in GNOME 49. Upstream GNOME plans to fully remove X11 support in GNOME 50.
See the release
notes for a full list of changes in Fedora 43.
Lab9 Pro is the B2B division of Lab9, Belgium’s leading Apple Premium Partner. With over 30 years of experience, Lab9 Pro specializes in integrating and supporting Apple systems within businesses, educational institutions, and public organizations. Beyond Apple expertise, Lab9 Pro also designs, implements, and maintains complete IT infrastructures, including networks, servers, storage, and security solutions.
The challenge
It’s impossible to manage devices at organizations without the use of a good MDM (Mobile Device Management) system such as Jamf. As the leading provider of Apple device management solutions, Jamf empowers organizations to deploy, manage, and secure Apple devices at scale.
Even in smaller organizations Jamf is the right solution, as small and medium-sized enterprises (SMEs) often lack the resources to manage their MDM systems. Offering an MSP model solves a lot of problems for these customers.
For Apple device management, the typical customer has a few certificates issued by Apple, which require approval of the user agreement by the Apple business or school manager. Without getting too technical about Apple Device management, depending on the customer the certificates need to be renewed on different dates. If the user agreement is not approved, automated device enrollment will stop working.
Lab9 Pro found themselves needing to check all certificates and user agreements for MSP customers manually, which involved an unacceptably high error rate that often caused discontinuity of the MDM system.
The solution
Lab9 Pro were already using Zabbix to monitor customer environments and their own infrastructure, including storage, firewalls, switches, and more. Because Zabbix offers a wide variety of options that make it possible to monitor almost anything, it was only logical to explore whether Zabbix could also be used to monitor the MDM certificates.
The research phase
Step one was to check the availability of certificate information. Unfortunately, Apple Business Manager’s API did not help much, as it does not provide certificate details. Instead, the team at Lab9 Pro investigated the Jamf API.
Although it doesn’t directly return certificate information either, they found something even more useful – Jamf’s API provides customer instance notifications. These include alerts when certificates (VPP, PUSH, DEP, etc.) are about to expire (typically 10 days in advance) as well as when the Device Enrollment Program (user agreement) is not approved.
Zabbix implementation
Since Lab9 Pro manages multiple MSP tenants, they created a dedicated Zabbix template. This template includes both pre-filled and empty macros:
Pre-filled macros:
• {$JAMF.AUTH.INTERVAL}: Interval for retrieving the bearer token
• {$JAMF.NOTIF.INTERVAL}: Interval for retrieving Jamf notifications
• {$JAMF.PATH.AUTH}: API path for retrieving the bearer token
• {$JAMF.PATH.NOTIFICATIONS}: API path for retrieving Jamf notifications
Empty macros:
• {$JAMF.URL}: Jamf URL
• {$JAMF.API.USER}: Jamf user account for authentication
• {$JAMF.API.PASSWORD}: Jamf password (stored as a secret value)
The team configured an item to perform an API call to retrieve the bearer token. A preprocessing rule in JavaScript stores this token in a variable. Discovery rules proved very useful for executing API calls to retrieve Jamf notifications using the bearer token. This was achieved by configuring preprocessing steps and Low-Level Discovery (LLD) macros to pass the Jamf URL and bearer token. Trigger prototypes for each certificate were also added within the same discovery rule.
The results
Whenever a certificate is nearing expiration, a problem is automatically displayed on Lab9 Pro’s Zabbix dashboard, which is visible on TV screens placed throughout their office in order to make sure the entire team is aware of upcoming certificate renewals.
Since Lab9 Pro began monitoring MDM certificates through the Jamf API, they have experienced zero expired certificates, which in turn has allowed them to avoid situations where devices become unmanaged and require a full setup again.
Zabbix makes it possible for Lab9 Pro to keep their clients’ MDM systems operational, while allowing them to either proactively inform them when certificates need to be renewed or handle the renewal process on their behalf.
This week, the last week of October 2025, we reached a major milestone for Internet security: the majority of human-initiated traffic with Cloudflare is using post-quantum encryption mitigating the threat of harvest-now/decrypt-later.
We want to use this joyous moment to give an update on the current state of the migration of the Internet to post-quantum cryptography and the long road ahead. Our last overview was 21 months ago, and quite a lot has happened since. A lot of it has been passed as we predicted: finalization of the NIST standards; broad adoption of post-quantum encryption; more detailed roadmaps from regulators; progress on building quantum computers; some cryptography was broken (not to worry: nothing close to what’s deployed); and new exciting cryptography was proposed.
But there were also a few surprises: there was a giant leap in progress towards Q-day by improving quantum algorithms, and we had a proper scare because of a new quantum algorithm. We’ll cover all this and more: what we expect for the coming years; and what you can do today.
The quantum threat
First things first: why are we changing our cryptography? It’s because of quantum computers. These marvelous devices, instead of restricting themselves to zeroes and ones, compute using more of what nature actually affords us: quantum superposition, interference, and entanglement. This allows quantum computers to excel at certain very specific computations, notably simulating nature itself, which will be very helpful in developing new materials.
Quantum computers are not going to replace regular computers, though: they’re actually much worse than regular computers at most tasks that matter for our daily lives. Think of them as graphic cards or neural engines — specialized devices for specific computations, not general-purpose ones.
Unfortunately, quantum computers also excel at breaking key cryptography that still is in common use today, such as RSA and elliptic curves (ECC). Thus, we are moving to post-quantum cryptography: cryptography designed to be resistant against quantum attack. We’ll discuss the exact impact on the different types of cryptography later on.
For now, quantum computers are rather anemic: they’re simply not good enough today to crack any real-world cryptographic keys. That doesn’t mean we shouldn’t worry yet: encrypted traffic can be harvested today, and decrypted after Q-day: the day that quantum computers are capable of breaking today’s still widely used cryptography such as RSA-2048. We call that a “harvest-now-decrypt-later” attack.
Using factoring as a benchmark, quantum computers don’t impress at all: the largest number factored by a quantum computer without cheating is 15, a record that’s easily beaten in a variety of funny ways. It’s tempting to disregard quantum computers until they start beating classical computers on factoring, but that would be a big mistake. Even conservative estimates place Q-day less than three years after the day that quantum computers beat classical computers on factoring. So how do we track progress?
Quantum numerology
There are two categories to consider in the march towards Q-day: progress on quantum hardware, and algorithmic improvements to the software that runs on that hardware. We have seen significant progress on both fronts.
Progress on quantum hardware
Like clockwork, every year there are news stories of new quantum computers with record-breaking number of qubits. This focus on counting qubits is also quite misleading. To start, quantum computers are analogue machines, and there is always some noise interfering with the computation.
There are big differences between the different types of technology used to build quantum computers: silicon-based quantum computers seem to scale well, are quick to execute instructions, but have very noisy qubits. This does not mean they’re useless: with quantum error correcting codes one can effectively turn millions of noisy silicon qubits into a few thousand high-fidelity ones, which could be enough to break RSA. Trapped-ion quantum computers, on the other hand, have much less noise, but have been harder to scale. Only a few hundred-thousand trapped-ion qubits could potentially draw the curtain on RSA-2048.
Timelapse of state-of-art in quantum computing from 2021 through 2025 by qubit count on the x-axis and noise on the y-axis. The dots in the gray area are the various quantum computers out there. Once the shaded gray area hits the left-most red line, we’re in trouble as that means a quantum computer can break large RSA keys. Compiled by Samuel Jaques of the University of Waterloo.
We’re only scratching the surface with the number of qubits and noise. There are low-level details that can make a big difference, such as the interconnectedness of qubits. More importantly, the graph doesn’t capture how scalable the engineering behind the records is.
To wit, on these graphs the progress on quantum computers seems to have stalled the last two years, whereas for experts, Google’s December 2024 Willow announcement that is unremarkable on the graph, is in reality a real milestone achieving the first logical qubit in the surface code in a scalable manner. Quoting Sam Jaques:
When I first read these results [Willow’s achievements], I felt chills of “Oh wow, quantum computing is actually real”.
It’s a real milestone, but not an unexpected leap. Quoting Sam again:
Despite my enthusiasm, this is more or less where we should expect to be, and maybe a bit late. All of the big breakthroughs they demonstrated are steps we needed to take to even hope to reach the 20 million qubit machine that could break RSA. There are no unexpected breakthroughs. Think of it like the increases in transistor density of classical chips each year: an impressive feat, but ultimately business-as-usual.
Business-as-usual is also the strategy: the superconducting qubit approach pursued by Google for Willow has always had the clearest path forward attacking the difficulties head-on requiring fewest leaps in engineering.
Microsoft pursues the opposite strategy with their bet on topological qubits. These are qubits that in theory would mostly not be unaffected by noise. However, they have not been fully realized in hardware. If these can be built in a scalable way, they’d be far superior to superconducting qubits. But we don’t even know if these can be built to begin with. Early 2025 Microsoft announced the Majorana 1 chip, which demonstrates how these could be built. The chip is far from a full demonstrator though: it doesn’t support any computation and hence doesn’t even show up in Sam’s comparison graph earlier.
In between topological and superconducting qubits, there are many other approaches that labs across the world pursue that do show up in the graph, such as QuEra with neutral atoms and Quantinuum with trapped ions.
Progress on the hardware side of getting to Q-day has received by far the most amount of press interest. The biggest breakthrough in the last two years isn’t on the hardware side though.
Progress on quantum software
The biggest breakthrough so far: Craig Gidney’s optimisations
We thought we’d need about 20 million qubits with the superconducting approach to break RSA-2048. It turns out we can do it with much less. In a stunningly comprehensive June 2025 paper, Craig Gidney shows that with clever quantum software optimisations we need fewer than one million qubits. This is the reason the red lines in Sam’s graph above, marking the size of a quantum computer to break RSA, dramatically shift to the left in 2025.
To put this achievement into perspective, let’s just make a wild guess and say Google can maintain a sort of Moore’s law and doubles the number of physical qubits every one-and-a-half years. That’s a much faster pace than Google demonstrated so far, but it’s also not unthinkable they could achieve this once the groundwork has been laid. Then it’d take until 2052 to reach 20 million qubits, but only until 2045 to reach one million: Craig single-handedly brought Q-day seven years closer!
How much further can software optimisations go? Pushing it lower than 100,000 superconducting qubits seems impossible to Sam, and he’d expect more than 242,000 superconducting qubits are required to break RSA-2048. With the wild guess on quantum computer progress before, that’d correspond to a Q-day of 2039 and 2041+ respectively.
Although Craig’s estimate makes detailed and reasonable assumptions on the architecture of a large-scale superconducting qubits quantum computer, it’s still a guess, and these estimates could be off quite a bit.
A proper scare: Chen’s algorithm
On the algorithmic side, we might not only see improvements to existing quantum algorithms, but also the discovery of completely new quantum algorithms. April 2024, Yilei Chen published a preprint claiming to have found such a new quantum algorithm to solve certain lattice problems, which are close, but not the same as those we rely on for the post-quantum cryptography we deploy. This caused a proper stir: even if it couldn’t attack our post-quantum algorithms today, could Chen’s algorithm be improved? To get a sense for potential improvements, you need to understand what the algorithm is really doing on a higher level. With Chen’s algorithm that’s hard, as it’s very complex, much more so than Shor’s quantum algorithm that breaks RSA. So it took some time for experts to startseeing limitations to Chen’s approach, and in fact, after ten days they discovered a fundamental bug in the algorithm: the approach doesn’t work. Crisis averted.
What to take from this? Optimistically, this is business as usual for cryptography, and lattices are in a better shape now as one avenue of attack turned out to be a dead end. Realistically, it is a reminder that we have a lot of eggs in the lattices basket. As we’ll see later, presently there isn’t a real alternative that works everywhere.
Proponents of quantum key distribution (QKD) might chime in that QKD solves exactly that by being secure thanks to the laws of nature. Well, there are some asterixes to put on that claim, but more fundamentally no one has figured out how to scale QKD beyond point-to-point connections, as we argue in this blog post.
It’s good to speculate about what cryptography might be broken by a completely new attack, but let’s not forget the matter at hand: a lot of cryptography is going to be broken by quantum computers for sure. Q-day is coming; the question is when.
Is Q-day always fifteen years away?
If you’ve been working on or around cryptography and security long enough, then you have probably heard that “Q-day is X years away” every year for the last several years. This can make it feel like Q-day is always “some time in the future” — until we put such a claim in the proper context.
What do experts think?
Since 2019, the Global Risk Institute has performed a yearly survey amongst experts, asking how probable it is that RSA-2048 will be broken within 5, 10, 15, 20 or 30 years. These are the results for 2024, whose interviews happened before Willow’s release and Gidney’s breakthrough.
Global Risk Institute expert survey results from 2024 on the likelihood of a quantum computer breaking RSA-2048 within different timelines.
As the middle column in this chart shows, well over half of the interviewed experts thought there was at least a ~50% chance that a quantum computer will break RSA-2048 within 15 years. Let’s look up the historical answers from 2019, 2020, 2021, 2022, and 2023. Here we plot the likelihood for Q-day within 15 years (of the time of the interview):
Historical answers in the quantum threat timeline reports for the chance of Q-day within 15 years.
This shows that answers are slowly trending to more certainty, but at the rate we would expect? With six years of answers, we can plot how consistent the predictions are over a year: does the 15-year estimate for 2019 match the 10-year estimate for 2024?
Historical answers in the quantum threat timeline report over the years on the date of Q-day. The x-axis is the alleged year for Q-day and the y-axis shows the fraction of interviewed experts that think it’s at least ~50% (left) or 70% (right) likely to happen then.
If we ask experts when Q-day could be with about even odds (graph on the left), then they mostly keep saying the same thing over the years: yes, could be 15 years away. However, if we press for more certainty, and ask for Q-day with >70% probability (graph on the right), then the experts are mostly consistent over the years. For instance: one-fifth thought 2034 both in the 2019 and 2024 interviews.
So, if you want a consistent answer from an expert, don’t ask them when Q-day could be, but when it’s probably there. Now, it’s good fun to guess about Q-day, but the honest answer is that no one really knows for sure: there are just too many unknowns. And in the end, the date of Q-day is far less important than the deadlines set by regulators.
What action do regulators take?
We can also look at the timelines of various regulators. In 2022, the National Security Agency (NSA) released their CNSA 2.0 guidelines, which has deadlines between 2030 and 2033 for migrating to post-quantum cryptography. Also in 2022, the US federal government set 2035 as the target to have the United States fully migrated, from which the new administration hasn’t deviated. In 2024 Australia set 2030 as their aggressive deadline to migrate. Early 2025, the UK NCSC matched the common 2035 as the deadline for the United Kingdom. Mid-2025, the European Union published their roadmap with 2030 and 2035 as deadlines depending on the application.
Far from all national regulators have provided post-quantum migration timelines, but those that do generally stick to the 2030–2035 timeframe.
When is Q-day?
So when will quantum computers start causing trouble? Whether it’s 2034 or 2050, for sure it will be too soon. The immense success of cryptography over fifty years means it’s all around us now, from dishwasher, to pacemaker, to satellite. Most upgrades will be easy, and fit naturally in the product’s lifecycle, but there will be a long tail of difficult and costly upgrades.
Now, let’s take a look at the migration to post-quantum cryptography.
Mitigating the quantum threat: two migrations
To help prioritize, it is important to understand that there is a big difference in the difficulty, impact, and urgency of the post-quantum migration for the different kinds of cryptography required to create secure connections. In fact, for most organizations there will be two post-quantum migrations: key agreement and signatures / certificates. Let’s explain this for the case of creating a secure connection when visiting a website in a browser.
The cryptographic workhorse of a connection is a symmetric cipher such as AES-GCM. It’s what you would think of when thinking of cryptography: both parties, in this case the browser and server, have a shared key, and they encrypt / decrypt their messages with the same key. Unless you have that key, you can’t read anything, or modify anything.
The good news is that symmetric ciphers, such as AES-GCM, are already post-quantum secure. There is a common misconception that Grover’s quantum algorithm requires us to double the length of symmetric keys. On closer inspection of the algorithm, it’s clear that it is notpractical. The way NIST, the US National Institute for Standards and Technology (who have been spearheading the standardization of post-quantum cryptography) defines their post-quantum security levels is very telling. They define a specific security level by saying the scheme should be as hard to crack using either a classical or quantum computer as an existing symmetric cipher as follows:
Level
Definition, as least as hard to break as …
Example
1
To recover the key of AES-128 by exhaustive search
ML-KEM-512, SLH-DSA-128s
2
To find a collision in SHA256 by exhaustive search
ML-DSA-44
3
To recover the key of AES-192 by exhaustive search
ML-KEM-768, ML-DSA-65
4
To find a collision in SHA384 by exhaustive search
5
To recover the key of AES-256 by exhaustive search
ML-KEM-1024, SLH-DSA-256s, ML-DSA-87
NIST PQC security levels, higher is harder to break (“more secure”). The examples ML-DSA, SLH-DSA and ML-KEM are covered below.
There are good intentions behind suggesting doubling the key lengths of symmetric cryptography. In many use cases, the extra cost is not that high, and it mitigates any theoretical risk completely. Scaling symmetric cryptography is cheap: double the bits is typically far less than half the cost. So on the surface, it is simple advice.
But if we insist on AES-256, it seems only logical to insist on NIST PQC level 5 for the public key cryptography as well. The problem is that public key cryptography does not scale very well. Depending on the scheme, going from level 1 to level 5 typically more than doubles data usage and CPU cost. As we’ll see, deploying post-quantum signatures at level 1 is already painful, and deploying them at level 5 is debilitating.
But more importantly, organizations only have limited resources. We wouldn’t want an organization to prioritize upgrading AES-128 at the cost of leaving the definitely quantum-vulnerable RSA around.
First migration: key agreement
Symmetric ciphers are not enough on their own: how do I know which key to use when visiting a website for the first time? The browser can’t just send a random key, as everyone listening in would see that key as well. You’d think it’s impossible, but there is some clever math to solve this, so that the browser and server can agree on a shared key. Such a scheme is called a key agreement mechanism, and is performed in the TLS handshake. In 2024 almost all traffic is secured with X25519, a Diffie–Hellman-style key agreement, but its security is completely broken by Shor’s algorithm on a quantum computer. Thus, any communication secured today with Diffie–Hellman, when stored, can be decrypted in the future by a quantum computer.
This makes it urgent to upgrade key agreement today. Luckily post-quantum key agreement is relatively straight-forward to deploy, and as we saw before, half the requests with Cloudflare end 2025 are already secured with post-quantum key agreement!
Second migration: signatures / certificates
The key agreement allows secure agreement on a key, but there is a big gap: we do not know with whom we agreed on the key. If we only do key agreement, an attacker in the middle can do separate key agreements with the browser and server, and re-encrypt any exchanged messages. To prevent this we need one final ingredient: authentication.
This is achieved using signatures. When visiting a website, say cloudflare.com, the web server presents a certificate signed by a certification authority (CA) that vouches that the public key in that certificate is controlled by cloudflare.com. In turn, the web server signs the handshake and shared key using the private key corresponding to the public key in the certificate. This allows the client to be sure that they’ve done a key agreement with cloudflare.com.
RSA and ECDSA are commonly used traditional signature schemes today. Again, Shor’s algorithm makes short work of them, allowing a quantum attacker to forge any signature. That means that an attacker with a quantum computer can impersonate (and MitM) any website for which we accept non post-quantum certificates.
This attack can only be performed after quantum computers are able to crack RSA / ECDSA. This makes upgrading signature schemes for TLS on the face of it less urgent, as we only need to have everyone migrated before Q-day rolls around. Unfortunately, we will see that migration to post-quantum signatures is much more difficult, and will require more time.
Progress timeline
Before we dive into the technical challenges of migrating the Internet to post-quantum cryptography, let’s have a look at how we got here, and what to expect in the coming years. Let’s start with how post-quantum cryptography came to be.
Origin of post-quantum cryptography
Physicists Feynman and Manin independently proposed quantum computers around 1980. It took another 14 years before Shor published his algorithm attacking RSA / ECC. Most post-quantum cryptography predates Shor’s famous algorithm.
There are various branches of post-quantum cryptography, of which the most prominent are lattice-based, hash-based, multivariate, code-based, and isogeny-based. Except for isogeny-based cryptography, none of these were initially conceived as post-quantum cryptography. In fact, early code-based and hash-based schemes are contemporaries of RSA, being proposed in the 1970s, and comfortably predate the publication of Shor’s algorithm in 1994. Also, the first multivariate scheme from 1988 is comfortably older than Shor’s algorithm. It is a nice coincidence that the most successful branch, lattice-based cryptography, is Shor’s closest contemporary, being proposed in 1996. For comparison, elliptic curve cryptography, which is widely used today, was first proposed in 1985.
In the years after the publication of Shor’s algorithm, cryptographers took measure of the existing cryptography: what’s clearly broken, and what could be post-quantum secure? In 2006, the first annual International Workshop on Post-Quantum Cryptography took place. From that conference, an introductory text was prepared, which holds up rather well as an introduction to the field. A notable caveat is the demise of the Rainbow signature scheme. In that same year, 2006, the elliptic-curve key-agreement X25519 was proposed, which now secures the majority of Internet connections, either on its own or as a hybrid with the post-quantum ML-KEM-768.
NIST completes the first generation of PQC standards
Ten years later, in 2016, NIST, the US National Institute of Standards and Technology, launched a public competition to standardize post-quantum cryptography. They used a similar open format as was used to standardize AES in 2001, and SHA3 in 2012. Anyone can participate by submitting schemes and evaluating the proposals. Cryptographers from all over the world submitted algorithms. To focus attention, the list of submissions were whittled down over three rounds. From the original 82, based on public feedback, eight made it into the final round. From those eight, in 2022, NIST chose to pick four to standardize first: one KEM (for key agreement) and three signature schemes.
Old name
New name
Branch
Kyber
ML-KEM (FIPS 203)
Module-lattice based Key-Encapsulation Mechanism Standard
FN-DSA (not standardised yet) FFT over NTRU lattices Digital Signature Standard
Lattice-based
The final standards for the first three have been published August 2024. FN-DSA is late and we’ll discuss that later.
ML-KEM is the only post-quantum key agreement standardised now, and despite some occasional difficulty with its larger key sizes, it’s mostly a drop-in upgrade.
The situation is rather different with the signatures: it’s quite telling that NIST chose to pursue standardising three already. And there are even more signatures set to be standardized in the future. The reason is that none of the proposed signatures are close to ideal. In short, they all have much larger keys and signatures than we’re used to.
From a security standpoint SLH-DSA is the most conservative choice, but also the worst performer. For public key and signature sizes, FN-DSA is as good as it gets for these three, but it is difficult to implement signing safely because of floating-point arithmetic. Due to FN-DSA’s limited applicability and design complexity, NIST chose to focus on the other three schemes first.
This leaves ML-DSA as the default pick. More in depth comparisons are included below.
Adoption of PQC in protocol standards
Having NIST’s standards is not enough. It’s also required to standardize the way the new algorithms are used in higher level protocols. In many cases, such as key agreement in TLS, this can be as simple as assigning an identifier to the new algorithms. In other cases, such as DNSSEC, it requires a bit more thought. Many working groups at the IETF have been preparing for years for the arrival of NIST’s final standards, and we expected many protocol integrations to be finalized soon after, before the end of 2024. That was too optimistic: some are done, but many are not finished yet.
Let’s start with the good news and look at what is done.
The hybrid TLS key agreement X25519MLKEM768 that combines X25519 and ML-KEM-768 (more about it later) is ready to use and is indeed quite widely deployed. Other protocols are likewise adopting ML-KEM in a hybrid mode of operation, such as IPsec, which is ready to go for simple setups. (For certain setups, there is a litle wrinkle that still needs to be figured out. We’ll cover that in a future blog post.)
It might be surprising that the corresponding RFCs have not been published yet. Registering a key agreement to TLS or IPsec does not require an RFC though. In both cases, the RFC is still being pursued to avoid confusion for those that would expect an RFC, and for TLS it’s required to mark the key agreement as recommended.
For signatures, ML-DSA’s integration in X.509 certificates and TLS are good to go. The former is a freshly minted RFC, and the latter doesn’t require one.
Now, for the bad news. At the time of writing, October 2025, the IETF hasn’t locked down how to do hybrid certificates: certificates where both a post-quantum and a traditional signature scheme are combined. But it’s close. We hope this’ll be figured out early 2026.
But if it’s just assigning some identifiers, what’s the cause of the delay? Mostly it’s about choice. Let’s start with the choices that had to be made in ML-DSA.
ML-DSA delays: much ado about prehashing and private key formats
The two major topics of discussion for ML-DSA certificates were prehashing and the private key format.
Prehashing is where one part of the system hashes the message, and another creates the final signatures. This is useful, if you don’t want to send a big file to an HSM to sign. Early drafts of ML-DSA support prehashing with SHAKE256, but that was not obvious. In the final version of ML-DSA, NIST included two variants: regular ML-DSA, and an explicitly prehashed version, where you are allowed to choose any hash. Having different variants is not ideal, as users will have to choose which one to pick; not all software might support all variants; and testing/validation has to be done for all. It’s not controversial to want to pick just one variant, but the issue iswhich. After plenty of debate, regular ML-DSA was chosen.
The second matter is private key format. Because of the way that candidates are compared on performance benchmarks, it looks good for the original ML-DSA submission to cache some computation in the private key. This means that the private key is larger (several kilobytes) than it needs to be and requires more validation steps. It was suggested to cut the private key down to its bare essentials: just a 32-byte seed. For the final standard, NIST decided to allow both the seed and the original larger private key. This is not ideal: better stick to one of the two. In this case, the IETF wasn’t able to make a choice, and even added a third option: a pair of both the seed and expanded private key. Technically almost everyone agreed that seed is the superior choice, but the reason it wasn’t palatable is that some vendors already created keys for which they didn’t keep the seed around. Yes, we already have post-quantum legacy. It took almost a year to make these two choices.
Hybrids require many choices
To define an ML-DSA hybrid signature scheme, there are many more choices to make. With which traditional scheme to combine ML-DSA? What security levels on both sides. Then we also need to make choices for both schemes: which private key format to use? Which hash to use with ECDSA? Hybrids have new questions of their own. Do we allow reuse of the keys in the hybrid, and for that, do we want to prevent stripping attacks? Also, the question of prehashing returns with a third option: prehash on the hybrid level.
The October 2025 draft for ML-DSA hybrid signatures contains 18 variants, down from 26 a year earlier. Again, everyone agrees that that is too much, but it’s been hard to whittle it down further. To help end-users choose, a short list was added, which started with three options, and of course grew itself to six. Of those, we think MLDSA44-ECDSA-P256-SHA256 will see wide support and use on the Internet.
Now, let’s return to key agreement for which the standards have been set.
TLS stacks get support for ML-KEM
The next step is software support. Not all ecosystems can move at the same speed, but we’ve seen major adoption of post-quantum key agreement to counter store-now/decrypt-later already. Recent versions of all major browsers, and many TLS libraries and platforms, notably OpenSSL, Go, and recent Apple OSes have enabled X25519MLKEM768 by default. We keep an overview here.
Again, for TLS there is a big difference again between key agreement and signatures. For key agreement, the server and client can add and enable support for post-quantum key agreement independently. Once enabled on both sides, TLS negotiation will use post-quantum key agreement. We go into detail on TLS negotiation in this blog post. If your product just uses TLS, your store-now/decrypt-now problem could be solved by a simple software update of the TLS library.
Post-quantum TLS certificates are more of a hassle. Unless you control both ends, you’ll need to install two certificates: one post-quantum certificate for the new clients, and a traditional one for the old clients. If you aren’t using automated issuance of certificates yet, this might be a good reason to check that out. TLS allows the client to signal which signature schemes it supports so that the server can choose to serve a post-quantum certificate only to those clients that support it. Unfortunately, although almost all TLS libraries support setting up multiple certificates, not all servers expose that configuration. If they do, it will still require a configuration change in most cases. (Although undoubtedly caddy will do it for you.)
Talking about post-quantum certificates: it will take some time before Certification Authorities (CAs) can issue them. Their HSMs will first need (hardware) support, which then will need to be audited. Also, the CA/Browser forum needs to approve the use of the new algorithms. Root programs have different opinions about timelines. From the grapevine, we hear one of the root programs is preparing a pilot to accept one-year ML-DSA-87 certificates, perhaps even before the end of 2025. A CA/Browser forum ballot is being drafted to support this. Chrome on the other hand, prefers to solve the large certificate issue first. For the early movers, the audits are likely to be the bottleneck, as there will be a lot of submissions after the publication of the NIST standards. Although we’ll see the first post-quantum certificates in 2026, it’s unlikely they will be broadly available or trusted by all browsers before 2027.
We are in an interesting in-between time, where a lot of Internet traffic is protected by post-quantum key agreement, but not a single public post-quantum certificate is used.
The search continues for more schemes
NIST is not quite done standardizing post-quantum cryptography. There are two more post-quantum competitions running: round 4 and the signatures onramp.
Round 4 winner: HQC
NIST only standardized one post-quantum key agreement so far: ML-KEM. They’d like to have a second one, a backup KEM, not based on lattices in case those turn out to be weaker than expected. To find it, they extended the original competition with a fourth round to pick a backup KEM among the finalists. In March 2025, HQC was selected to be standardized.
HQC performs much worse than ML-KEM on every single metric. HQC-1, the lowest security level variant, requires 7kB of data on the wire. This is almost double the 3kB required for ML-KEM-1024, the highest security level variant. There is a similar gap in CPU performance. Also HQC scales worse with security level: where ML-KEM-1024 is about double the cost of ML-KEM-512, the highest security level of HQC requires three times the data (21kB!) and more than four times the compute.
What about the security? To hedge against gradually improved attacks, ML-KEM-768 has a clear edge over HQC-1, it performs much better, and it has a huge security margin at level 3 compared to level 1. What about leaps? Both ML-KEM and HQC use a similar algebraic structure on top of plain lattices and codes respectively: it is not inconceivable that a breakthrough there could apply to both. Now, also without the algebraic structure, codes and lattices feel related. We’re well into speculation: a catastrophic attack on lattices might not affect codes, but it wouldn’t be surprising too if it did. After all, RSA and ECC that are more dissimilar are both broken by quantum computers.
There might still be peace of mind to keep HQC around just in case. Here, we’d like to share an anecdote from the chaotic week when it was not clear yet that Chen’s quantum algorithm against lattices was flawed. What to replace ML-KEM with if it would be affected? HQC was briefly considered, but it was clear that an adjusted variant of ML-KEM would still be much more performant.
Stepping back: that we’re looking for a second efficient KEM is a luxury position. If I were granted a wish for a new post-quantum scheme, I wouldn’t ask for a better KEM, but for a better signature scheme. Let’s see if I get lucky.
Signatures onramp
In late 2022, after announcing the first four picks, NIST also called a new competition, dubbed the signatures onramp, to find additional signature schemes. The competition has two goals. The first is hedging against cryptanalytic breakthroughs against lattice-based cryptography. NIST would like to standardize a signature that performs better than SLH-DSA (both in size and compute), but is not based on lattices. Secondly, they’re looking for a signature scheme that might do well in use cases where the current roster doesn’t do well: we will discuss those at length later on in this post.
In July 2023, NIST posted the 40 submissions they received for a first round of public review. The cryptographic community got to work, and as is quite normal for a first round, many of the schemes were broken within a week. By February 2024, ten submissions were broken completely, and several others were weakened drastically. Out of the standing candidates, in October 2024, NIST selected 14 submissions for the second round.
A year ago, we wrote a blog post covering these 14 submissions in great detail. The short of it: there has been amazing progress on post-quantum signature schemes. We will touch briefly upon them later on, and give some updates on the advances since last year. It is worth mentioning that just like the main post-quantum competition, the selection process will take many years. It is unlikely that any of these onramp signature schemes will be standardized before 2028 — if they’re not broken in the first place. That means that although they’re very welcome in the future, we can’t trust that better signature schemes will solve our problems today. As Eric Rescorla, the editor of TLS 1.3, writes: “You go to war with the algorithms you have, not the ones you wish you had.”
With that in mind, let’s look at the progress of deployments.
Migrating the Internet to post-quantum key agreement
Now that we have the big picture, let’s dive into some finer details about this X25519MLKEM768 that’s widely deployed now.
First the post-quantum part. ML-KEM was submitted under the name CRYSTALS-Kyber. Even though it’s a US standard, its designers work in industry and academia across France, Switzerland, the Netherlands, Belgium, Germany, Canada, China, and the United States. Let’s have a look at its performance.
ML-KEM versus X25519
Today the vast majority of clients use the traditional key agreement X25519. Let’s compare that to ML-KEM.
Size and CPU compared between X25519 and ML-KEM. Performance varies considerably by hardware platform and implementation constraints, and should be taken as a rough indication only.
ML-KEM-512, -768 and -1024 aim to be as resistant to (quantum) attack as AES-128, -192 and -256 respectively. Even at the AES-128 level, ML-KEM is much bigger than X25519, requiring 800+768=1,568 bytes over the wire, whereas X25519 requires a mere 64 bytes.
On the other hand, even ML-KEM-1024 is typically significantly faster than X25519, although this can vary quite a bit depending on your platform and implementation.
ML-KEM-768 and X25519
We are not taking advantage of that speed boost just yet. Like many other early adopters, we like to play it safe and deploy a hybrid key-agreement combining X25519 and ML-KEM-768. This combination might surprise you for two reasons.
Why combine X25519 (“128 bits of security”) with ML-KEM-768 (“192 bits of security”)?
Why bother with the non post-quantum X25519?
The apparent security level mismatch is a hedge against improvements in cryptanalysis in lattice-based cryptography. There is a lot of trust in the (non post-quantum) security of X25519: matching AES-128 is more than enough. Although we are comfortable in the security of ML-KEM-512 today, over the coming decades cryptanalysis could improve. Thus, we’d like to keep a margin for now.
The inclusion of X25519 has two reasons. First, there is always a remote chance that a breakthrough renders all variants of ML-KEM insecure. In that case, X25519 still provides non-post-quantum security, and our post-quantum migration didn’t make things worse.
More important is that we do not only worry about attacks on the algorithm, but also on the implementation. A noteworthy example where we dodged a bullet is that of KyberSlash, a timing attack that affected many implementations of Kyber (an earlier version of ML-KEM), including our own. Luckily KyberSlash does not affect Kyber as it is used in TLS. A similar implementation mistake that would actually affect TLS, is likely to require an active attacker. In that case, the likely aim of the attacker wouldn’t be to decrypt data decades down the line, but steal a cookie or other token, or inject a payload. Including X25519 prevents such an attack.
So how well do ML-KEM-768 and X25519 together perform in practice?
Performance and protocol ossification
Browser experiments
Being well aware of potential compatibility and performance issues, Google started a first experiment with post-quantum cryptography back in 2016, the same year NIST started their competition. This was followed up by a second larger joint experiment by Cloudflare and Google in 2018. We tested two different hybrid post-quantum key agreements: CECPQ2, which is a combination of the lattice-based NTRU-HRSS and X25519, and CECPQ2b, a combination of the isogeny-based SIKE and again X25519. NTRU-HRSS is very similar to ML-KEM in size, but is computationally somewhat more taxing on the client-side. SIKE on the other hand, has very small keys, is computationally very expensive, and was completely broken in 2022. With respect to TLS handshake times, X25519+NTRU-HRSS performed very well.
Unfortunately, a small but significant fraction of clients experienced broken connections with NTRU-HRSS. The reason: the size of the NTRU-HRSS keyshares. In the past, when creating a TLS connection, the first message sent by the client, the so-called ClientHello, almost always fit within a single network packet. The TLS specification allows for a larger ClientHello, however no one really made use of that. Thus, protocol ossification strikes again as there are some middleboxes, load-balancers, and other software that tacitly assume the ClientHello always fits in a single packet.
Long road to 50%
Over the subsequent years, we kept experimenting with PQ, switching to Kyber in 2022, and ML-KEM in 2024. Chrome did a great job reaching out to vendors whose products were incompatible. If it were not for these compatibility issues, we would’ve likely seen Chrome ramp up post-quantum key agreement five years earlier. It took until March 2024 before Chrome felt comfortable enough to enable post-quantum key agreement by default on Desktop. After that many other clients, and all major browsers, have joined Chrome in enabling post-quantum key agreement by default. An incomplete timeline:
Apple is rolling out PQ by default with the release of iOS / iPadOS / macOS 26.
It’s noteworthy that there is a gap between Chrome enabling PQ on Desktop and on Android. Although ML-KEM doesn’t have a large performance impact, as seen in the graphs, it’s certainly not negligible, especially on the long tail of slower connections more prevalent on mobile, and it required more consideration to proceed.
But we’re finally here now: over 50% (and rising!) of human traffic is protected against store-now/decrypt-later, making post-quantum key agreement the new security baseline for the Web.
Browsers are one side of the equation, what about servers?
Server-side support
Back in 2022 we enabled post-quantum key agreement server side for basically all customers. Google did the same for most of their servers (except GCP) in 2023. Since then many have followed. Jan Schaumann has been posting regular scans of the top 100k domains. In his September 2025 post, he reports 39% support PQ now, up from 28% only six months earlier. In his survey, we see not only support rolling out on large service providers, such as Amazon, Fastly, Squarespace, Google, and Microsoft, but also a trickle of self-hosted servers adding support hosted at Hetzner and OVHcloud.
This is the publicly accessible web. What about servers behind a service like Cloudflare?
Support at origins
In September 2023, we added support for our customers to enable post-quantum key agreement on connections from Cloudflare to their origins. That’s connection (3) in the following diagram:
Typical connection flow when a visitor requests an uncached page.
Back in 2023 only 0.5% of origins supported post-quantum key agreement. Through 2024 that hasn’t changed much. This year, in 2025, we see support slowly pick up with software support rolling out, and we’re now at 3.7%.
Fraction of origins that support the post-quantum key agreement X25519MLKEM768.
3.7% doesn’t sound impressive at all compared to the previous 50% and 39% for clients and public servers respectively, but it’s nothing to scoff at. There is much more diversity in origins than there are in clients: many more people have to do something to make that number move up. But it’s still a more than seven-fold increase, and let’s not forget that back in 2024 we celebrated reaching 1.8% of client support.For customers, origins aren’t always easy to upgrade at all. Does that mean missing out on post-quantum security? No, not necessarily: you can secure the connection between Cloudflare and your origin by setting up Cloudflare Tunnel as a sidecar to your origin.
Ossification
Support is all well and good, but as we saw with browser experiments, protocol ossification is a big concern. What does it look like with origins? Well, it depends.
There are two ways to enable post-quantum key agreement: the fast way, and the slow but safer way. In both cases, if the origin doesn’t support post-quantum, they’ll fall back safely to traditional key agreement. We explain the details in this blog post, but in short, in the fast way we send the post-quantum keys immediately, and in the safer way we postpone it by one roundtrip using HelloRetryRequest. All major browsers use the fast way.
We have been regularly scanning all origins to see what they support. The good news is that all origins supported the safe but slow method. The fast method didn’t fare as well, as we found that 0.05% of connections would break. That’s too high to enable the fast method by default. We did enable PQ to origins using the safer method by default for all non-enterprise customers and enterprise customers can opt in.
We are not satisfied though until it’s fast and enabled for everyone. That’s why we’ll automatically enable post-quantum to origins using the fast method for all customers, if our scans show it’s safe.
Internal connections
So far all the connections we’ve been talking about are between Cloudflare and external parties. There are also a lot of internal connections within Cloudflare (marked 2 in the two diagrams above.) In 2023 we made a big push to upgrade our internal connections to post-quantum key agreement. Compared to all the other post-quantum efforts we pursue, this has been, by far, the biggest job: we asked every engineering team in the company to stop what they’re doing; take stock of the data and connections that their products secure; and upgrade them to post-quantum key agreement. In most cases the upgrade was simple. In fact, many teams were already upgraded by pulling in software updates. Still, figuring out that you’re already done can take quite some time! On a positive note, we didn’t see any performance or ossification issues in this push.
We have upgraded the majority of internal connections, but a long tail remains, which we continue to work on. The most important connection that we didn’t get to upgrade in 2023 is the connection between WARP client and Cloudflare. In September 2025 we upgraded it, by moving from Wireguard to QUIC.j
Outlook
As we’ve seen, post-quantum key agreement, despite initial trouble with protocol ossification, has been straightforward to deploy. In the vast majority of cases it’s an uneventful software update. And with 50% deployment (and rising), it’s the new security baseline for the Internet.
Let’s turn to the second, more difficult migration.
Migrating the Internet to post-quantum signatures
Now, we’ll turn our attention to upgrading the signatures used on the Internet.
The zoo of post-quantum signatures
We wrote a long deep dive in the field of post-quantum signature schemes last year, November 2024. Most of that is still up-to-date, but there have been some exciting developments. Here we’ll just go over some highlights and some exciting updates of last year.
Let’s start by sizing up the post-quantum signatures we have available today at the AES-128 security level: ML-DSA-44 and the two variants of SLH-DSA. We use ML-DSA-44 as the baseline, as that’s the scheme that’s going to see the most widespread use initially. As a comparison, we also include the venerable Ed25519 and RSA-2048 in wide use today, as well as FN-DSA-512 which will be standardised soon and a sample of nine for TLS promising signature schemes from the signatures onramp.
Comparison of various signature schemes at the security level of AES-128. CPU times vary significantly by platform and implementation constraints and should be taken as a rough indication only. ⚠️ FN-DSA signing time when using fast but dangerous floating-point arithmetic — see warning below. ⚠️ SQISign signing is not timing side-channel secure.
It is immediately clear that none of the post-quantum signature schemes comes even close to being a drop-in replacement for Ed25519 (which is comparable to ECDSA P-256) as most of the signatures are simply much bigger. The exceptions are SQISign, MAYO, SNOVA, and UOV from the onramp, but they’re far from ideal. MAYO, SNOVA, and UOV have large public keys, and SQISign requires a great amount of computation.
Be careful with FN-DSA
Looking ahead a bit: the best of the first competition seems to be FN-DSA-512. FN-DSA-512’s signatures and public key together are only 1,563 bytes, with somewhat reasonable signing time. FN-DSA has an achilles heel though — for acceptable signing performance, it requires fast floating-point arithmetic. Without it, signing is about 20 times slower. But speed is not enough, as the floating-point arithmetic has to run in constant time — without it, the FN-DSA private key can be recovered by timing signature creation. Writing safe FN-DSA implementations has turned out to be quite challenging, which makes FN-DSA dangerous when signatures are generated on the fly, such as in a TLS handshake. It is good to stress that this only affects signing. FN-DSA verification does not require floating-point arithmetic (and during verification there wouldn’t be a private key to leak anyway.)
There are many signatures on the web
The biggest pain-point of migrating the Internet to post-quantum signatures, is that there are a lot of signatures even in a single connection. When you visit this very website for the first time, we send five signatures and two public keys.
The majority of these are for the certificate chain: the CA signs the intermediate certificate, which signs the leaf certificate, which in turn signs the TLS transcript to prove the authenticity of the server. If you’re keeping count: we’re still two signatures short.
These are for SCTs required for certificate transparency. Certificate transparency (CT) is a key, but lesser known, part of the Web PKI, the ecosystem that secures browser connections. Its goal is to publicly log every certificate issued, so that misissuances can be detected after the fact. It’s the system that’s behind crt.sh and Cloudflare Radar. CT has shown its value once more very recently by surfacing a rogue certificate for 1.1.1.1.
Certificate transparency works by having independent parties run CT logs. Before issuing a certificate, a CA must first submit it to at least two different CT logs. An SCT is a signature of a CT log that acts as a proof, a receipt, that the certificate has been logged.
Tailoring signature schemes
There are two aspects of how a signature can be used that are worthwhile to highlight: whether the public key is included with the signature, and whether the signature is online or offline.
For the SCTs and the signature of the root on the intermediate, the public key is not transmitted during the handshake. Thus, for those, a signature scheme with smaller signatures but larger public keys, such as MAYO, SNOVA, or UOV, would be particularly well-suited. For the other signatures, the public key is included, and it’s more important to minimize the sizes of the combined public key and signature.
The handshake signature is the only signature that is created online — all the other signatures are created ahead of time. The handshake signature is created and verified only once, whereas the other signatures are typically verified many times by different clients. This means that for the handshake signature, it’s advantageous to balance signing and verification time which are both in the hot path, whereas for the other signatures having better verification time at the cost of slower signing is worthwhile. This is one of the advantages RSA still enjoys over elliptic curve signatures today.
Putting together different signature schemes is a fun puzzle, but it also comes with some drawbacks. Using multiple different schemes increases the attack surface because an algorithmic or implementation vulnerability in one compromises the whole. Also, the whole ecosystem needs to implement and optimize multiple algorithms, which is a significant burden.
Putting it together
So, what are some reasonable combinations to try?
With NIST’s current picks
With the draft standards available today, we do not have a lot of options.
If we simply switch to ML-DSA-44 for all signatures, we’re adding 15kB of data that needs to be transmitted from the server to the client during the TLS handshake. Is that a lot? Probably. We will address that later on.
If we wait a bit and replace all but the handshake signature with FN-DSA-512, we’re looking at adding only 7kB. That’s much better, but I have to repeat that it’s difficult to implement FN-DSA-512 signing safely without timing side channels, and there is a good chance we’ll shoot ourselves in the foot if we’re not careful. Another way to shoot ourselves in the foot today is with stateful hash-based signatures, as we explain here. All in all, FN-DSA-512 and stateful hash-based signatures tempt us with a similar and clear performance benefit over ML-DSA-44, but are difficult to use safely.
Signatures on the horizon
There are some promising new signature schemes submitted to the NIST onramp.
Purely looking at sizes, SQISign I is the clear winner, even beating RSA-2048. Unfortunately, the computation required for signing, and crucially verification, are too high. SQISign is in a worse position than FN-DSA with implementation security: it’s very complicated and it’s unclear how to perform signing in constant time. For niche applications, SQISign might be useful, but for general adoption verification times need to improve significantly, even if that requires a larger signature. Over the last few years there has been amazing progress in improving verification time; simplifying the algorithm; and implementation security for (variants of) SQISign. They’re not there yet, but the gap has shrunk much more than we’d have expected. If the pace of improvement holds, then a future SQISign could well be viable for TLS.
One conservative contender is UOV (unbalanced oil and vinegar). It is an old multivariate scheme with a large public key (66.5kB), but small signatures (96 bytes). Over the decades, there have been many attempts to add some structure to UOV public keys, to get a better balance between public key and signature size. Many of these so-called structured multivariate schemes, which includes Rainbow and GeMMS, unfortunately have been broken dramatically “with a laptop over the weekend”. MAYO and SNOVA, which we’ll get to in a bit, are the latest attempts at structured multivariate. UOV itself has remained mostly unscathed. Surprisingly in 2025, Lars Ran found a completely new “wedges” attack on UOV. It doesn’t affect UOV much, although SNOVA and MAYO are hit harder. Why the attack is noteworthy, is that it’s based on a relatively simple idea: it is surprising it wasn’t found before. Now, getting back to performance: if we combine UOV for the root and SCTs with ML-DSA-44 for the others, we’re looking at only 10kB — close to FN-DSA-512.
Now, let’s to the main event:
The fight between MAYO versus SNOVA
Looking at the roster today, MAYO and particularly SNOVA look great from a performance standpoint. Last year, SNOVA and MAYO were closer in performance, but they have diverged quite a bit.
MAYO is designed by the cryptographer that broke Rainbow. As a structured multivariate scheme, its security requires careful scrutiny, but its utility (assuming it is not broken) is very appealing. MAYO allows for a fine-grained tradeoff between signature and public key size. For the submission, to keep things simple, the authors proposed two concrete variants: MAYOone with balanced signature (454 bytes) and public key (1.4kB) sizes, and MAYOtwo that has signatures of 216 bytes, while keeping the public key manageable at 4.3kB. Verification times are excellent, while signing times are somewhat slower than ECDSA, but far better than RSA. Combining both variants in the obvious way, we’re only looking at 4.3kB. These numbers are a bit higher than last year, as MAYO adjusted its parameters again slightly to account for newly discovered attacks.
Over the competition, SNOVA has been hit harder by attacks than MAYO. SNOVA’s response has been more aggressive: instead of just tweaking parameters to adjust, they have also made larger changes to the internals of the scheme, to counter the attacks and to get a performance improvement to boot. Combining SNOVA(37,17,16,2) and SNOVA(24,5,23,4) in the obvious way, we’re looking at adding just an amazing 2.1kB.
We see a face-off shaping up between the risky but much smaller SNOVA, and the conservative but slower MAYO. Zooming out, both have very welcome performance, and both are too risky to deploy now. Ran’s new wedges attack is an example that the field of multivariate cryptanalysis still holds surprises, and needs more eyes and time. It’s too soon to pick a winner between SNOVA and MAYO: let them continue to compete. Even if they turn out to be secure, neither is likely to be standardized 2029, which means we cannot rely on them for the initial migration to post-quantum authentication.
Stepping back, is the 15kB for ML-DSA-44 actually that bad?
Do we really care about the extra bytes?
On average, around 18 million TLS connections are established with Cloudflare per second. Upgrading each to ML-DSA, would take 2.1Tbps, which is 0.5% of our current total network capacity. No problem so far. The question is how these extra bytes affect performance.
It will take 15kB extra to swap in ML-DSA-44. That’s a lot compared to the typical handshake today, but it’s not a lot compared to the JavaScript and images served on many web pages. The key point is that the change we must make here affects every single TLS connection, whether it’s used for a bloated website, or a time-critical API call. Also, it’s not just about waiting a bit longer. If you have spotty cellular reception, that extra data can make the difference between being able to load a page, and having the connection time out. (As an aside, talking about bloat: many apps perform a surprisingly high number of TLS handshakes.
Just like with key agreement, performance isn’t our only concern: we also want the connection to succeed in the first place. Back in 2021, we ran an experiment artificially enlarging the certificate chain to simulate larger post-quantum certificates. We summarize the result here. One key take-away is that some clients or middleboxes don’t like certificate chains larger than 10kB. This is problematic for a single-certificate migration strategy. In this approach, the server installs a single traditional certificate that contains a separate post-quantum certificate in a so-called non-critical extension. A client that does not support post-quantum certificates will ignore the extension. In this approach, installing the single certificate will immediately break all clients with compatibility issues, making it a non-starter. On the performance side there is also a steep drop in performance at 10kB because of the initial congestion window.
Is 9kB too much? The slowdown in TLS handshake time would be approximately 15%. We felt the latter is workable, but far from ideal: such a slowdown is noticeable and people might hold off deploying post-quantum certificates before it’s too late.
Chrome is more cautious and set 10% as their target for maximum TLS handshake time regression. They report that deploying post-quantum key agreement has already incurred a 4% slowdown in TLS handshake time, for the extra 1.1kB from server-to-client and 1.2kB from client-to-server. That slowdown is proportionally larger than the 15% we found for 9kB, but that could be explained by slower upload speeds than download speeds.
There has been pushback against the focus on TLS handshake times. One argument is that session resumption alleviates the need for sending the certificates again. A second argument is that the data required to visit a typical website dwarfs the additional bytes for post-quantum certificates. One example is this 2024 publication, where Amazon researchers have simulated the impact of large post-quantum certificates on data-heavy TLS connections. They argue that typical connections transfer multiple requests and hundreds of kilobytes, and for those the TLS handshake slowdown disappears in the margin.
Are session resumption and hundreds of kilobytes over a connection typical though? We’d like to share what we see. We focus on QUIC connections, which are likely initiated by browsers or browser-like clients. Of all QUIC connections with Cloudflare that carry at least one HTTP request, 27% are resumptions, meaning that key material from a previous TLS connection is reused, avoiding the need to transmit certificates. The median number of bytes transferred from server-to-client over a resumed QUIC connection is 4.4kB, while the average is 259kB. For non-resumptions the median is 8.1kB and average is 583kB. This vast difference between median and average indicates that a small fraction of data-heavy connections skew the average. In fact, only 15.5% of all QUIC connections transfer more than 100kB.
The median certificate chain today (with compression) is 3.2kB. That means that almost 40% of all data transferred from server to client on more than half of the non-resumed QUIC connections are just for the certificates, and this only gets worse with post-quantum algorithms. For the majority of QUIC connections, using ML-DSA-44 as a drop-in replacement for classical signatures would more than double the number of transmitted bytes over the lifetime of the connection.
It sounds quite bad if the vast majority of data transferred for a typical connection is just for the post-quantum certificates. It’s still only a proxy for what is actually important: the effect on metrics relevant to the end-user, such as the browsing experience (e.g. largest contentful paint) and the amount of data those certificates take from a user’s monthly data cap. We will continue to investigate and get a better understanding of the impact.
Way forward for post-quantum authentication
The path for migrating the Internet to post-quantum authentication is much less clear than with key agreement. Unless we can get performance much closer to today’s authentication, we expect the vast majority to keep post-quantum authentication disabled. Postponing enabling post-quantum authentication until Q-day draws near carries a real risk that we will not see the issues before it’s too late to fix. That’s why it’s essential to make post-quantum authentication performant enough to be turned on by default.
We’re exploring various ideas to reduce the number of signatures, in increasing order of ambition: leaving out intermediates; KEMTLS; and Merkle Tree Certificates. We covered these in detail last year. Most progress has been made on the last one: Merkle Tree Certificates (MTC). In this proposal, in the common case, all signatures except the handshake signature are replaced by a short <800 byte Merkle tree proof. This could well allow for post-quantum authentication that’s actually faster than using traditional certificates today! Together with Chrome, we’re going to try it out by the end of the year: read about it in this blog post.
Not just TLS, authentication, and key agreement
Despite its length, in this blog post, we have only really touched upon migrating TLS. And even TLS we did not cover completely, as we have not discussed Encrypted ClientHello (we didn’t forget about it). Although important, TLS is not the only protocol key to the security of the Internet. We want to briefly mention a few other challenges, but cannot go into detail. One particular challenge is DNSSEC, which is responsible for securing the resolution of domain names.
Although key agreement and signatures are the most widely used cryptographic primitives, over the last few years we have seen the adoption of more esoteric cryptography to serve more advanced use cases, such as unlinkable tokens with Privacy Pass / PAT, anonymous credentials, and attribute based encryption to name a few. For most of these advanced cryptographic schemes, there is no known practical post-quantum alternative yet. Although to our delight there have been great advances in post-quantum anonymous credentials.
What you can do today to stay safe against quantum attacks
To summarize, there are two main post-quantum migrations to keep an eye on: key agreement, and certificates.
We recommend moving to post-quantum key agreement to counter store-now/decrypt-later attacks, which only requires a software update on both sides. That means that with the quick adoption (we’re keeping a list) of X25519MLKEM768 across software and services, you might well be secure already against store-now/decrypt-later! On Cloudflare Radar you can check whether your browser supports X25519MLKEM768; if you use Firefox, there is an extension to check support of websites while you visit; you can scan whether your website supports it here; and you can use Wireshark to check for it on the wire.
Those are just spot checks. For a proper migration, you’ll need to figure out where cryptography is used. That’s a tall order, as most organizations have a hard time tracking all software, services, and external vendors they use in the first place. There will be systems that are difficult to upgrade or have external dependencies, but in many cases it’s simple. In fact, in many cases, you’ll spend a lot of time to find out that they are already done.
As figuring out what to do is the bulk of the work, it’s perhaps tempting to split that out as a first milestone: create a detailed inventory first; the so-called cryptographic bill of materials (CBOM). Don’t let an inventory become a goal on its own: we need to keep our eyes on the ball. Most cases are easy: if you figured out what to do to migrate in one case, don’t wait and context switch, but just do it. That doesn’t mean it’ll be fast: this is a marathon not a sprint, but you’ll be surprised how much ground can be covered by getting started.
Certificates. At the time of writing this blog in October 2025, the final standards for post-quantum certificates are not set yet. Hopefully that won’t take too long to resolve. But there is much that you can do now to prepare for post-quantum certificates that you won’t regret at all. Keep software up-to-date. Automate certificate issuance. Ensure you can install multiple certificates.
In case you’re worried about protocol ossification, there is no reason to wait: the final post-quantum standards will not be very different from the draft. You can test with preliminary implementations (or large dummy certificates) today.
The post-quantum migration is quite unique. Typically, if cryptography is broken, it’s either sudden or gradually making it easy to ignore for a time. In both cases, migrations in the end are rushed. With the quantum threat, we know for sure that we’ll need to replace a lot of cryptography, but we also have time. Instead of just a chore, we invite you to see this as an opportunity: we have to do maintenance now on many systems that rarely get touched. Instead of just hotfixes, now is the opportunity to rethink past choices.
At least, if you start now. Good luck with your migration, and if you hit any issues, do reach out: [email protected]
The world is in a race to build its first quantum computer capable of solving practical problems not feasible on even the largest conventional supercomputers. While the quantum computing paradigm promises many benefits, it also threatens the security of the Internet by breaking much of the cryptography we have come to rely on.
To mitigate this threat, Cloudflare is helping to migrate the Internet to Post-Quantum (PQ) cryptography. Today, about 50% of traffic to Cloudflare’s edge network is protected against the most urgent threat: an attacker who can intercept and store encrypted traffic today and then decrypt it in the future with the help of a quantum computer. This is referred to as the harvest now, decrypt laterthreat.
However, this is just one of the threats we need to address. A quantum computer can also be used to crack a server’s TLS certificate, allowing an attacker to impersonate the server to unsuspecting clients. The good news is that we already have PQ algorithms we can use for quantum-safe authentication. The bad news is that adoption of these algorithms in TLS will require significant changes to one of the most complex and security-critical systems on the Internet: the Web Public-Key Infrastructure (WebPKI).
The central problem is the sheer size of these new algorithms: signatures for ML-DSA-44, one of the most performant PQ algorithms standardized by NIST, are 2,420 bytes long, compared to just 64 bytes for ECDSA-P256, the most popular non-PQ signature in use today; and its public keys are 1,312 bytes long, compared to just 64 bytes for ECDSA. That’s a roughly 20-fold increase in size. Worse yet, the average TLS handshake includes a number of public keys and signatures, adding up to 10s of kilobytes of overhead per handshake. This is enough to have a noticeable impact on the performance of TLS.
That makes drop-in PQ certificates a tough sell to enable today: they don’t bring any security benefit before Q-day — the day a cryptographically relevant quantum computer arrives — but they do degrade performance. We could sit and wait until Q-day is a year away, but that’s playing with fire. Migrations always take longer than expected, and by waiting we risk the security and privacy of the Internet, which is dear to us.
It’s clear that we must find a way to make post-quantum certificates cheap enough to deploy today by default for everyone — not just those that can afford it. In this post, we’ll introduce you to the plan we’ve brought together with industry partners to the IETF to redesign the WebPKI in order to allow a smooth transition to PQ authentication with no performance impact (and perhaps a performance improvement!). We’ll provide an overview of one concrete proposal, called Merkle Tree Certificates (MTCs), whose goal is to whittle down the number of public keys and signatures in the TLS handshake to the bare minimum required.
But talk is cheap. We knowfromexperience that, as with any change to the Internet, it’s crucial to test early and often. Today we’re announcing our intent to deploy MTCs on an experimental basis in collaboration with Chrome Security. In this post, we’ll describe the scope of this experiment, what we hope to learn from it, and how we’ll make sure it’s done safely.
The WebPKI today — an old system with many patches
Why does the TLS handshake have so many public keys and signatures?
Let’s start with Cryptography 101. When your browser connects to a website, it asks the server to authenticate itself to make sure it’s talking to the real server and not an impersonator. This is usually achieved with a cryptographic primitive known as a digital signature scheme (e.g., ECDSA or ML-DSA). In TLS, the server signs the messages exchanged between the client and server using its secret key, and the client verifies the signature using the server’s public key. In this way, the server confirms to the client that they’ve had the same conversation, since only the server could have produced a valid signature.
If the client already knows the server’s public key, then only 1 signature is required to authenticate the server. In practice, however, this is not really an option. The web today is made up of around a billion TLS servers, so it would be unrealistic to provision every client with the public key of every server. What’s more, the set of public keys will change over time as new servers come online and existing ones rotate their keys, so we would need some way of pushing these changes to clients.
This scaling problem is at the heart of the design of all PKIs.
Trust is transitive
Instead of expecting the client to know the server’s public key in advance, the server might just send its public key during the TLS handshake. But how does the client know that the public key actually belongs to the server? This is the job of a certificate.
A certificate binds a public key to the identity of the server — usually its DNS name, e.g., cloudflareresearch.com. The certificate is signed by a Certification Authority (CA) whose public key is known to the client. In addition to verifying the server’s handshake signature, the client verifies the signature of this certificate. This establishes a chain of trust: by accepting the certificate, the client is trusting that the CA verified that the public key actually belongs to the server with that identity.
Clients are typically configured to trust many CAs and must be provisioned with a public key for each. Things are much easier however, since there are only 100s of CAs instead of billions. In addition, new certificates can be created without having to update clients.
These efficiencies come at a relatively low cost: for those counting at home, that’s +1 signature and +1 public key, for a total of 2 signatures and 1 public key per TLS handshake.
That’s not the end of the story, however. As the WebPKI has evolved, so have these chains of trust grown a bit longer. These days it’s common for a chain to consist of two or more certificates rather than just one. This is because CAs sometimes need to rotatetheir keys, just as servers do. But before they can start using the new key, they must distribute the corresponding public key to clients. This takes time, since it requires billions of clients to update their trust stores. To bridge the gap, the CA will sometimes use the old key to issue a certificate for the new one and append this certificate to the end of the chain.
That’s +1 signature and +1 public key, which brings us to 3 signatures and 2 public keys. And we still have a little ways to go.
Trust but verify
The main job of a CA is to verify that a server has control over the domain for which it’s requesting a certificate. This process has evolved over the years from a high-touch, CA-specific process to a standardized, mostly automated process used for issuing most certificates on the web. (Not all CAs fully support automation, however.) This evolution is marked by a number of security incidents in which a certificate was mis-issued to a party other than the server, allowing that party to impersonate the server to any client that trusts the CA.
Automation helps, but attacks are still possible, and mistakes are almost inevitable. Earlier this year, several certificates for Cloudflare’s encrypted 1.1.1.1 resolver were issued without our involvement or authorization. This apparently occurred by accident, but it nonetheless put users of 1.1.1.1 at risk. (The mis-issued certificates have since been revoked.)
Ensuring mis-issuance is detectable is the job of the Certificate Transparency (CT) ecosystem. The basic idea is that each certificate issued by a CA gets added to a public log. Servers can audit these logs for certificates issued in their name. If ever a certificate is issued that they didn’t request itself, the server operator can prove the issuance happened, and the PKI ecosystem can take action to prevent the certificate from being trusted by clients.
Major browsers, including Firefox and Chrome and its derivatives, require certificates to be logged before they can be trusted. For example, Chrome, Safari, and Firefox will only accept the server’s certificate if it appears in at least two logs the browser is configured to trust. This policy is easy to state, but tricky to implement in practice:
Operating a CT log has historically been fairly expensive. Logs ingest billions of certificates over their lifetimes: when an incident happens, or even just under high load, it can take some time for a log to make a new entry available for auditors.
Clients can’t really audit logs themselves, since this would expose their browsing history (i.e., the servers they wanted to connect to) to the log operators.
The solution to both problems is to include a signature from the CT log along with the certificate. The signature is produced immediately in response to a request to log a certificate, and attests to the log’s intent to include the certificate in the log within 24 hours.
Per browser policy, certificate transparency adds +2 signatures to the TLS handshake, one for each log. This brings us to a total of 5 signatures and 2 public keys in a typical handshake on the public web.
The future WebPKI
The WebPKI is a living, breathing, and highly distributed system. We’ve had to patch it a number of times over the years to keep it going, but on balance it has served our needs quite well — until now.
Previously, whenever we needed to update something in the WebPKI, we would tack on another signature. This strategy has worked because conventional cryptography is so cheap. But 5 signatures and 2 public keys on average for each TLS handshake is simply too much to cope with for the larger PQ signatures that are coming.
The good news is that by moving what we already have around in clever ways, we can drastically reduce the number of signatures we need.
Crash course on Merkle Tree Certificates
Merkle Tree Certificates (MTCs) is a proposal for the next generation of the WebPKI that we are implementing and plan to deploy on an experimental basis. Its key features are as follows:
All the information a client needs to validate a Merkle Tree Certificate can be disseminated out-of-band. If the client is sufficiently up-to-date, then the TLS handshake needs just 1 signature, 1 public key, and 1 Merkle tree inclusion proof. This is quite small, even if we use post-quantum algorithms.
The MTC specification makes certificate transparency a first class feature of the PKI by having each CA run its own log of exactly the certificates they issue.
Let’s poke our head under the hood a little. Below we have an MTC generated by one of our internal tests. This would be transmitted from the server to the client in the TLS handshake:
Looks like your average PEM encoded certificate. Let’s decode it and look at the parameters:
$ openssl x509 -in merkle-tree-cert.pem -noout -text
Certificate:
    Data:
        Version: 3 (0x2)
        Serial Number: 531 (0x213)
        Signature Algorithm: 1.3.6.1.4.1.44363.47.0
        Issuer: 1.3.6.1.4.1.44363.47.1=44363.48.3
        Validity
            Not Before: Oct 21 15:33:26 2025 GMT
            Not After : Oct 28 15:33:26 2025 GMT
        Subject: CN=cloudflareresearch.com
        Subject Public Key Info:
            Public Key Algorithm: id-ecPublicKey
                Public-Key: (256 bit)
                pub:
                    04:70:ed:e1:96:87:b4:22:ef:fb:dc:a9:cd:9c:5c:
                    ef:1e:9e:ab:1b:6d:d7:11:74:7b:76:c8:3c:a1:5f:
                    94:37:45:99:d8:80:e3:5c:24:4f:28:46:b5:bf:84:
                    60:d8:fc:eb:82:5a:c4:4e:33:90:c7:b3:36:51:0c:
                    92:6d:bf:88:27
                ASN1 OID: prime256v1
                NIST CURVE: P-256
        X509v3 extensions:
            X509v3 Key Usage: critical
                Digital Signature
            X509v3 Extended Key Usage:
                TLS Web Server Authentication
            X509v3 Subject Alternative Name:
                DNS:cloudflareresearch.com, DNS:static-ct.cloudflareresearch.com
    Signature Algorithm: 1.3.6.1.4.1.44363.47.0
    Signature Value:
        00:00:00:00:00:00:02:00:00:00:00:00:00:00:02:58:00:e0:
        44:be:03:a5:bd:6a:b7:f2:9e:39:77:4c:16:4c:f8:06:e5:e1:
        55:c0:93:21:c6:79:83:3c:dd:5b:e6:57:89:c0:75:b3:4c:ec:
        75:8a:0b:53:a0:ca:1c:07:0c:1a:92:dd:c7:7c:a2:23:5d:83:
        0e:e4:23:43:38:af:43:20:a8:66:44:34:95:87:ea:2b:f0:0f:
        16:52:bb:ea:67:67:1e:89:36:4f:90:d4:05:55:89:46:f1:b7:
        b6:68:84:d3:57:31:ae:2b:c3:79:31:86:85:9d:24:ed:cf:25:
        a4:5c:fd:8f:f6:76:14:55:dd:67:2e:df:d6:8c:25:0d:52:48:
        c8:e3:fe:f9:7c:e6:a5:30:52:a5:b5:c7:3a:89:a5:c1:f6:4b:
        5b:95:ef:70:b8:91:fc:61:0f:6d:16:de:39:e9:a0:59:49:2b:
        34:71:7c:2a:16:da:c7:af:de:f7:01:94:10:c4:62:d1:f5:00:
        87:bd:e8:a2:f4:df:3b:35:79:27:0e:fc:cc:43:e7:60:5a:df:
        df:06:e8:d3:7e:eb:b3:bf:7b:25:43:0f:34:9a:26:c0:d3:6d:
        5d:0c:28:bc:87:58:58:15:00:00
While some of the parameters probably look familiar, others will look unusual. On the familiar side, the subject and public key are exactly what we might expect: the DNS name is cloudflareresearch.com and the public key is for a familiar signature algorithm, ECDSA-P256. This algorithm is not PQ, of course — in the future we would put ML-DSA-44 there instead.
On the unusual side, OpenSSL appears to not recognize the signature algorithm of the issuer and just prints the raw OID and bytes of the signature. There’s a good reason for this: the MTC does not have a signature in it at all! So what exactly are we looking at?
The trick to leave out signatures is that a Merkle Tree Certification Authority (MTCA) produces its signatureless certificates in batches rather than individually. In place of a signature, the certificate has an inclusion proof of the certificate in a batch of certificates signed by the MTCA.
To understand how inclusion proofs work, let’s think about a slightly simplified version of the MTC specification. To issue a batch, the MTCA arranges the unsigned certificates into a data structure called a Merkle tree that looks like this:
Each leaf of the tree corresponds to a certificate, and each inner node is equal to the hash of its children. To sign the batch, the MTCA uses its secret key to sign the head of the tree. The structure of the tree guarantees that each certificate in the batch was signed by the MTCA: if we tried to tweak the bits of any one of the certificates, the treehead would end up having a different value, which would cause the signature to fail.
An inclusion proof for a certificate consists of the hash of each sibling node along the path from the certificate to the treehead:
Given a validated treehead, this sequence of hashes is sufficient to prove inclusion of the certificate in the tree. This means that, in order to validate an MTC, the client also needs to obtain the signed treehead from the MTCA.
This is the key to MTC’s efficiency:
Signed treeheads can be disseminated to clients out-of-band and validated offline. Each validated treehead can then be used to validate any certificate in the corresponding batch, eliminating the need to obtain a signature for each server certificate.
During the TLS handshake, the client tells the server which treeheads it has. If the server has a signatureless certificate covered by one of those treeheads, then it can use that certificate to authenticate itself. That’s 1 signature,1 public key and 1 inclusion proof per handshake, both for the server being authenticated.
Now, that’s the simplified version. MTC proper has some more bells and whistles. To start, it doesn’t create a separate Merkle tree for each batch, but it grows a single large tree, which is used for better transparency. As this tree grows, periodically (sub)tree heads are selected to be shipped to browsers, which we call landmarks. In the common case browsers will be able to fetch the most recent landmarks, and servers can wait for batch issuance, but we need a fallback: MTC also supports certificates that can be issued immediately and don’t require landmarks to be validated, but these are not as small. A server would provision both types of Merkle tree certificates, so that the common case is fast, and the exceptional case is slow, but at least it’ll work.
Experimental deployment
Ever since early designs for MTCs emerged, we’ve been eager to experiment with the idea. In line with the IETF principle of “running code”, it often takes implementing a protocol to work out kinks in the design. At the same time, we cannot risk the security of users. In this section, we describe our approach to experimenting with aspects of the Merkle Tree Certificates design without changing any trust relationships.
Let’s start with what we hope to learn. We have lots of questions whose answers can help to either validate the approach, or uncover pitfalls that require reshaping the protocol — in fact, an implementation of an early MTC draft by Maximilian Pohl and Mia Celeste did exactly this. We’d like to know:
What breaks? Protocol ossification (the tendency of implementation bugs to make it harder to change a protocol) is an ever-present issue with deploying protocol changes. For TLS in particular, despite having built-in flexibility, time after time we’ve found that if that flexibility is not regularly used, there will be buggy implementations and middleboxes that break when they see things they don’t recognize. TLS 1.3 deployment took years longer than we hoped for this very reason. And more recently, the rollout of PQ key exchange in TLS caused the Client Hello to be split over multiple TCP packets, something that many middleboxes weren’t ready for.
What is the performance impact? In fact, we expect MTCs to reduce the size of the handshake, even compared to today’s non-PQ certificates. They will also reduce CPU cost: ML-DSA signature verification is about as fast as ECDSA, and there will be far fewer signatures to verify. We therefore expect to see a reduction in latency. We would like to see if there is a measurable performance improvement.
What fraction of clients will stay up to date? Getting the performance benefit of MTCs requires the clients and servers to be roughly in sync with one another. We expect MTCs to have fairly short lifetimes, a week or so. This means that if the client’s latest landmark is older than a week, the server would have to fallback to a larger certificate. Knowing how often this fallback happens will help us tune the parameters of the protocol to make fallbacks less likely.
In order to answer these questions, we are implementing MTC support in our TLS stack and in our certificate issuance infrastructure. For their part, Chrome is implementing MTC support in their own TLS stack and will stand up infrastructure to disseminate landmarks to their users.
As we’ve done in past experiments, we plan to enable MTCs for a subset of our free customers with enough traffic that we will be able to get useful measurements. Chrome will control the experimental rollout: they can ramp up slowly, measuring as they go and rolling back if and when bugs are found.
Which leaves us with one last question: who will run the Merkle Tree CA?
Bootstrapping trust from the existing WebPKI
Standing up a proper CA is no small task: it takes years to be trusted by major browsers. That’s why Cloudflare isn’t going to become a “real” CA for this experiment, and Chrome isn’t going to trust us directly.
Instead, to make progress on a reasonable timeframe, without sacrificing due diligence, we plan to “mock” the role of the MTCA. We will run an MTCA (on Workers based on our StaticCT logs), but for each MTC we issue, we also publish an existing certificate from a trusted CA that agrees with it. We call this the bootstrap certificate. When Chrome’s infrastructure pulls updates from our MTCA log, they will also pull these bootstrap certificates, and check whether they agree. Only if they do, they’ll proceed to push the corresponding landmarks to Chrome clients. In other words, Cloudflare is effectively just “re-encoding” an existing certificate (with domain validation performed by a trusted CA) as an MTC, and Chrome is using certificate transparency to keep us honest.
Conclusion
With almost 50% of our traffic already protected by post-quantum encryption, we’re halfway to a fully post-quantum secure Internet. The second part of our journey, post-quantum certificates, is the hardest yet though. A simple drop-in upgrade has a noticeable performance impact and no security benefit before Q-day. This means it’s a hard sell to enable today by default. But here we are playing with fire: migrations always take longer than expected. If we want to keep an ubiquitously private and secure Internet, we need a post-quantum solution that’s performant enough to be enabled by default today.
Merkle Tree Certificates (MTCs) solves this problem by reducing the number of signatures and public keys to the bare minimum while maintaining the WebPKI’s essential properties. We plan to roll out MTCs to a fraction of free accounts by early next year. This does not affect any visitors that are not part of the Chrome experiment. For those that are, thanks to the bootstrap certificates, there is no impact on security.
We’re excited to keep the Internet fast and secure, and will report back soon on the results of this experiment: watch this space! MTC is evolving as we speak, if you want to get involved, please join the IETF PLANTS mailing list.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.