Когато светът свърши, ще бъде неделя следобед, късен ноември към 6 вечерта. Улиците ще бъдат празни, боклукът ще стои неприбран, семействата – изпокарани. Всичко ще бъде както си е било, само светът ще свършва като котка, която умира тихо, зад къщата.
Светът ще свърши в неделя (в четвъртък умират поетите). Светът ще свърши в неделя (в понеделник вече няма да има вестници, съобщаващи края), затова предварително за последен път и това е, да си знаете, макар да е късно, светът ще свърши в неделя тихо и кротко, в съня си.
2.
Минах през църквата към Колумбийския университет – църква, джамия и синагога, кораб на всички религии (византийска основа). Вратата беше отворена, надникнах, две кохорти студенти се молеха. Молете се, викнах, молете се и надуйте хубаво органа, днес светът свършва. Към колко часа, попита свещеникът. Към шест – шест и половина, отвърнах, не мога да кажа точно, но не чакайте дълго отлагане. (По-късно извиках същото през портата на St. John the Divine, по-долу на 111-а и Амстердам авеню, но едва ли ме чуха).
И вървях из Горен Манхатън, който всъщност е Долен Харлем, и виках на всички: Светът ще се свършва в неделя следобед, светът ще се свършва, приберете се вкъщи навреме, светът ще се свършва, казах на някакъв Уитман, легнал на тротоара, fuck you, man, кресна ми той, колко пъти ще свършва и запали тревата…
Последният продавач на фалафел затвори фургона, седна отвън и запали цигара, за днес толкова, вика, и този свят свърши.
П.П.
Вечерта заваля дъжд. Една жена се обади на един мъж. Една изгубена котка се върна вкъщи. Един отворен прозорец се тръшна. Някъде готвеха супа, явно нещо в бульона спасява от краища, прибира ножовете.
И краят пак се отложи…
Георги Господинов Ню Йорк, ноември, 2022
Георги Господинов (р. 1968) e поет, писател, драматург и литературовед. Книгите му са публикувани на повече от 35 езика. Носител на Международен „Букър“ 2023 за романа „Времеубежище“. Влиза в литературата през 90-те със стихосбирката „Лапидариум“ (1992). Автор е на пет поетически книги досега, сред които „Черешата на един народ“ (1996), „Писма до Гаустин“ (2003) и „Там, където не сме“ (2016, Награда за поезия „Перото“). Френското издание на „Там, където не сме“ в превода на Мари Врина-Николов е финалист за наградата „Маларме“. Стихосбирките му са издадени още на италиански, немски, гръцки, румънски, чешки, унгарски и др. Негови стихотворения са публикувани в антологии на световната и европейската поезия. Господинов е поет, който често контрабандира поезия и в романите си. Най-новият му роман е „Градинарят и смъртта“.
Според Екатерина Йосифова „четящият стихотворение сутрин… добре понася другите часове“ от деня. Убедени, че поезията държи умовете ни будни, а сърцата – отворени, в края на всеки месец ви предлагаме по едно стихотворение. Защото и в най-смутни времена доброто стихотворение е добра новина.
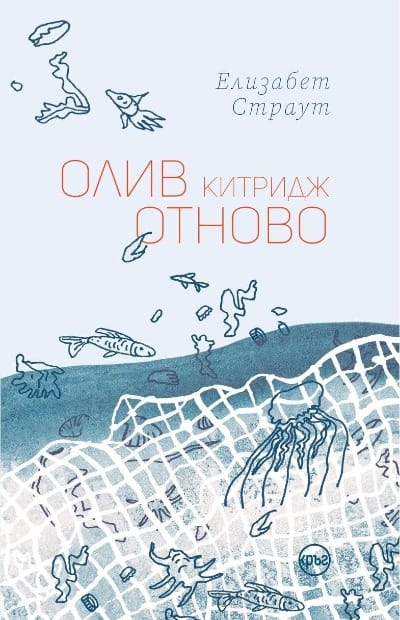
превод от английски Диляна Георгиева, София: изд. „Кръг“, 2023
Цяло десетилетие и един сериал дели първата и втората книга за Олив Китридж и всъщност е добре, че у нас преводите им се появиха достатъчно скоро един след друг. При всички случаи усещането е, че американската писателка Елизабет Страут, написала междувременно други два романа, изглежда, нито за миг не е изпускала от мисълта си своята необикновена героиня, защото този промеждутък изобщо не се усеща в продължението на едноименния роман.
Срещаме Олив отново малко след като сме я оставили да лежи до Джак, новия мъж в живота ѝ след смъртта на съпруга ѝ Хенри. В продължението Страут ни превежда през решението за повторния брак на героинята си и последвалите осем години съвместен живот до окончателно ѝ настаняване в старчески дом. И макар загубата и разрастващата се с годините самота, бавно изместваща ужаса от живота, да не са я смазали, Олив е неизбежно променена заради осъзнаванията под тежестта на времето. И все пак Олив е просто Олив – това определение, което авторката току използва, за да опише с две думи героинята си, е пределно изчерпателно само по себе си.
Преди няколко години българските читатели се влюбиха в тази директна, безцеремонна, винаги леко намусена и грубовата в отношението си, лишена от филтри и понякога почти аутистична в незачитането на общоприетото героиня. Причината бе, че зад нейния едър, не особено лицеприятен и дори леко занемарен вид, както и въпреки трудно поносимия ѝ нрав се таеше и другата ѝ страна: на емпатичен, справедлив, толерантен човек, интересуващ се от съдбата на другите. На прикрита зад тази фасада жена, обичана в крайна сметка от двама прекрасни мъже. Още повече че този неин едновременно семпъл, но многопластов и труден образ бе пресъздаден до съвършенство от голямата актриса Франсис Макдорманд в сериала на HBO.
Помня как още тогава, непреполовила първата книга, възкликнах:
Добре, защо по нашите ширини не се пише така – просто, но напоително, красиво, но без нито една излишна дума, проникновено, ала без грам претенция?
Не е случайно, че издаденият през 2008 г. първи роман бе отличен с наградата „Пулицър“. И в този
Страут не е изневерила на естествения си стил, на своя мръсен реализъм.
Да, винаги свързвам с американците това майсторство на разказването през несъбитийното, през пределно ежедневното, през уж небрежните разговори. Много трудно е всъщност да се пише за такива книги, в които нещата не са просто „казани“. В които драмата, тежестта, смисълът, големите прозрения се долавят ненатрапливо през рехавата тъкан на битовизмите, на почти случайните действия и лишените от апломб и афекти обстоятелства – и тъкмо затова удрят по-силно, защото са органична част от съществуването, нямат „специален статус“. Моментите на епифания, на преображение и осъзнаване, на съжаление и катарзис са тихи, незабележими, имплодиращи. А понякога просто красиво закъснели и тъжно безполезни.
Изумително е как може да се пише за остаряването (тази едва ли не най-скучна, най-малко привлекателна и досадна за читателите тема) без грам мелодраматичност и сантименталност, без тежест, без съжаление.
Графичният реализъм на старостта – с нейните бавни счупвания, попиващи памперси, напоителна самота, гравитационен колапс и липса на хоризонт – да потъва в меката есенна светлина, да бъде посрещан с олекотяваща ирония, с любимите на Олив изрази „глупости на търкалета“ и „върви по дяволите“.
Втората и може би неизбежно последна книга (макар че кой знае) е организирана по същия начин: в отделни разкази, които образуват рехаво споена романова цялост заради присъствието на Олив и заради общото място – същото провинциално крайбрежно градче Кросби в щата Мейн. И тук разказът е ту пряко за Олив (през нейната гледна точка), ту за други герои (през тяхната гледна точка), в чието ежедневие протагонистката се появява за кратко камео, в случайни срещи, за кратки посещения или просто колкото да размени с тях реплика или да им помаха от другия край на магазина. По този начин обаче се получава един фасетъчен образ, чиято централност оставя място за историите на куп други герои.
Въпросните истории са изпълнени с грешки, вини, лъжи, изневери, тайни, разочарования, предателства, слабости, болести, престъпления, самоубийства, отчуждение, скръб, смърт, срам, самота, провалено родителство и изгубени деца. И парадоксално, тъкмо поради това те звучат не прекомерни, а пределно обикновени, естествени, ежедневни. Страут успява да замаскира този житейски мащаб в лаконичност, в семпли щрихи, разкривайки промените по-късно и епизодично в следващите разкази.
Джак е развалил отношенията с дъщеря си, защото не може да приеме, че е лесбийка; пропилял е връзката с първата си съпруга заради извънбрачните им афери. Олив осъзнава, че се е провалила като майка по отношение на близостта си със своя син и че трудно приема семейството му, а той пък – повторния ѝ брак. Джак е саркастичен екстроверт, Олив е своеволен чешит. Историята на остаряването им обаче е и история на приемането, помиряването, протягането на ръка – било то и по нелеп начин, с всичките му дразнения и несъвършенства.
Недодяланата Олив ще съумее да живее с всичко онова, което я дразни в Джак, с
едрите им тела, захвърлени на брега като след корабокрушение и вкопчени на живот и смърт.
Ще открие женско приятелство насред упорития си индивидуализъм, ще преглътне предателството на поетеса, изложила едно към едно живота ѝ в своя творба, ще прости дори на болногледачката си, чиято ксенофобия и подкрепа за Тръмп категорично не желае да приеме.
Може би остаряването е именно това – загуба на твърдост.
„Олив отново“ е задължителна за прочит, ако вече сте прочели първата книга. Един роман в разкази за свързването дори когато то изглежда невъзможно; за намирането на изход в унинието и безнадеждността; за поемането на отговорност въпреки слабостта и усещането за изгубеност. За човека, който винаги трябва да бъде срещан отвъд политиката, съображенията и формалностите. И за грешките – онази субстанция на пределно човешкото, без която е невъзможно да съществуваме. За грешките със снизходителност и състрадание. Защото, както пише Страут за един от героите си,
тогава осъзна, че никога не бива да се омаловажава дълбоката човешка самота и че решенията, които хората вземат, за да се предпазят от зейналия мрак, изискват уважение.
Може би най-символичният диалог, който осмисля тези две книги за жителите на фиктивното провинциално градче, с привидната му скука и еднообразие, е следният: (Изкушавам се в края да го цитирам целия, защото звучи почти като идейно-програмен за този тип литература, която не се плаши от тривиалността и баналността, а ни превежда през тях, осмисляйки и обглеждайки ги, за да се открият пред нас дълбочините им.)
Бети я погледна:
– Моят живот ли? – попита тя и още сълзи се стекоха по лицето ѝ. – О, нали знаеш. – Тя махна леко с кърпичката във въздуха. – Ужасен – рече и се опита да се усмихне.
– Е, разкажи ми. Ще се радвам да те изслушам.
Бети още подсмърчаше, но и се усмихваше по-широко.
– О, Олив, обикновен живот.
Олив обмисли думите ѝ.
– Но е твоят живот. Има значение.
Активните дарители на „Тоест“ получават постоянна отстъпка в размер нa 20% от коричната цена на всички заглавия от каталога на издателство „Кръг“, както и на няколко други български издателства в рамките на партньорската програма Читателски клуб „Тоест“. За повече информация прочетете на toest.bg/club.
Никой от нас не чете единствено най-новите книги. Тогава защо само за тях се пише? „На второ четене“ е рубрика, в която отваряме списъците с книги, публикувани преди поне година, четем ги и препоръчваме любимите си от тях. Рубриката е част от партньорската програма Читателски клуб „Тоест“. Изборът на заглавия обаче е единствено на авторите – Стефан Иванов и Антония Апостолова, които биха ви препоръчали тези книги и ако имаше как веднъж на две седмици да се разходите с тях в книжарницата.
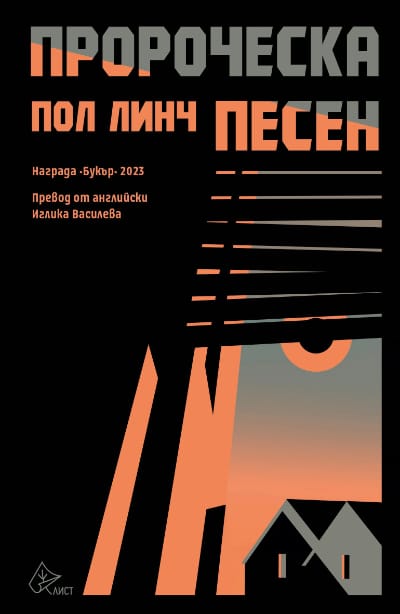
превод от английски Иглика Василева, София: изд. „Лист“, 2024
Когато съпругът на главната героиня изчезна, си казах: „Няма нужда.“ Няма нужда от книга, за да си представям, че това се случва тук – тази пророческа песен кънти в главата ми и бездруго. И да бягаш от новините, пак знаеш: знаеш, че случващото се в диктатурите по света може да се случи и тук. Ставало е, познаваш свидетели. Познаваш хора от други страни, на които се случва сега. Но следобедното слънце беше меко, а героинята гледаше мрака на верандата от топлината на стаята си. И тя, също като мен, знаеше и не знаеше.
Историята се разгръща в Ирландия, авторът е ирландец, тоест за нейните читатели тя звучи така, както би звучала книга, в която сме заменили Дамаск със София или Мариупол с Монтана. Премахната е защитната бариера на чуждото време или място.
Та в Ирландия се установява диктатура под невярващия поглед на хората от моя и вашия балон. Хора, които смятат, че могат да се борят с нея, като излизат на протести, като се сдружават в профсъюзи… Като правят правилните неща, които очакваме от хората по новините. Но „екранът“ в книгата не е този, на който се върти земното кълбо от „По света и у нас“. „Екранът“ е личната перспектива на главната героиня Айлиш, чийто мъж е учител и изчезва съвсем в началото – невярващ, че може да е нещо повече от разпит. Айлиш, която има четири деца. Айлиш, която също като мен не иска да вярва, че нейният свят се разпада. Не иска да вярва, че може да се отнася за нея. До най-покъртителния момент, в който отваря чувал след чувал в моргата и почти механично повтаря: „Не е моят син, не е моят син“. Докато е.
Впрочем другият много важен момент е малко преди това – когато се лута между болниците и вижда хора, седнали на слънце, да пият кафе. Вижда живота да продължава и разбира, че светът свършва, но не навсякъде, само нейният личен свят. Вижда невиждането на другите. Вижда – парадоксално – мен, която четох тази книга в спокойно кафене, обгърната в предпазния уют на красивия стил на Пол Линч, естествената сплитка на синтаксиса, майсторски преведена от Иглика Василева. Вижда мен от предишния си живот на свободна майка, която може да се разпознае в нея, но и да затвори книгата.
Но дори и затворена, „Пророческа песен“ продължава да се носи край нас.
„Черно хайку“ започва радикално точно с тази оптика: с погледа в упор към онова, което не искаме да видим. Още първата страница на стихосбирката на Яна Букова е програмна: гледане в смъртта, в нейната физическа реалност, но гледане отстрани, в спокоен разговор между мъртвите. Кои са тези безплътни гласове, които разговарят? Отвъдни? И да, и не. Това е гласът отвътре, гласът, който присъства само в съзнанието ни – и в литературата.
Авторът решава колко ще знае този глас – дали ще е всевиждащ, дали ще е заблуден, ограничен, неблагонадежден. Яна Букова иска той да знае всичко, и оттатък предела. Смъртта е само мярка, проверка за неговата истинност, преди човекът да види себе си. И тази истинност е винаги убеглива. Не само защото огледалата са сравнително отскоро. (Хубав въпрос е дали Ренесансът е изобретил огледалата, или възможността да се вгледаш в себе си е предизвикала Ренесанса.)
Извън техническата невъзможност да се видиш стои страхът да се видиш. С пленително сурова ерудиция Букова се вглежда в зрителя, който наблюдава катастрофата пред отнесената от торнадо четвърта стена на киносалона; в зрителя, който намира утеха в рамката от бодлива тел пред гледката; в зрителя, който изпитва копнеж по реда или отива да хапне нещо; в зрителя, който се запътва към хладилника, за да се утеши; в зрителя, който изключва звука. В себе си. Яна Букова не пропуска – нейната поезия продължава да чете новините, тяхното по-дълбоко значение, което ни се разкрива като буквална метафора. Като „дезинфекцираните подаръци“, които биха били метафора някога, но не и по време на ковид.
Защо е нужно това литературно всевиждане? Заради възможността за рефлексия, която тези стихотворения предлагат в изобилие. Споделянето на травмата не я лекува, показват изследванията, то само може да я умножи във всяко нейно разказване. Това, което помага, е нейното осмисляне. Стихотворенията в „Черно хайку“ съдържат опит за осмисляне на всичко, включително на черните петна. И да, това осмисляне се случва само в парадокса на коана, който е и парадоксът на поезията. Но се случва.
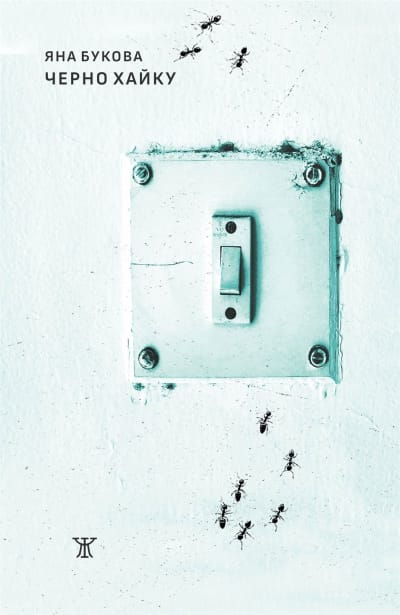
Хубава корица на Иво Рафаилов с превключвател – „прекъсвач“ на мястото на костта от стихотворението.
„Огледално“ значи и „точно обратното“. И като читателско преживяване стихосбирката „Кайротични прелюди“ изглежда огледална на „Черно хайку“. Тя сама ни предлага аналогията с ранения Андрей от битката при Аустерлиц във „Война и мир“: насред сражението отправяме поглед нагоре и изведнъж виждаме небето – виждаме го за пръв път, „във висотата отвъд навика“, казва авторът. И още: „след дълго гледане проглеждаш, оживяваш след години живот“. Това значи „кайротичен“ момент, внезапна, мимолетна пълнота на живота.
И самата книга е сгъстена в такива моменти – във внезапно отваряне на сетивото, блясване на смисъл, ненадейно насищане на живота. Това отваряне е навън и навътре; авторът описва вътрешните усещания така, както описва птиците – наблюдава ги внимателно, вслушва се в отсенките на песента им, отбелязва особеностите на оперението им – и непринудено ни води към родството на това чувство с музикален пасаж, с книга, с картина.
Ненатрапчива, топла ерудиция – няма значение дали познаваш произведението, още по-хубаво е, ако го срещаш за пръв път. Аз се изкушавам да си пускам музиката, да проверявам картините, да си поръчвам книгите; колко хубаво, че още толкова неща не знам, че мога да ги науча. Но и да науча нещо за себе си, докато се губя в картината. Това е интимно говорене за изкуство, то не занимава егото ми на читател, а чувствата; и не предлага да ги възпитава, а да ги приеме – като равни – сред изразените в изкуството. Подобно е говоренето на Ролан Барт, у нас може би на Цветан Стоянов. Елегантно и без декорации – сводовете са високи, думите са носещи елементи.
Бягство ли е тази височина, погледът нагоре насред сражението? Ни най-малко. Вижте последната глава.
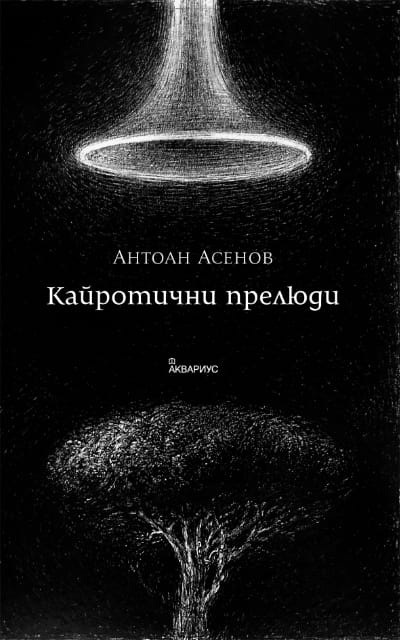
Извънредно ми е приятно, че тази книга е българска, както и предишната от същия автор – „Потос“, която пък беше посветена на копнежа. Много бих се радвала да намерят път и в други страни, защото тяхната дълбочина е универсална. Прекрасно уловена тук от корицата на Кирил Златков – краят на меден духов инструмент и дърво; музиката като високата нота към нашата природа, музиката като вслушване в природата ни. Защото тази тръба може да бъде и слухова.
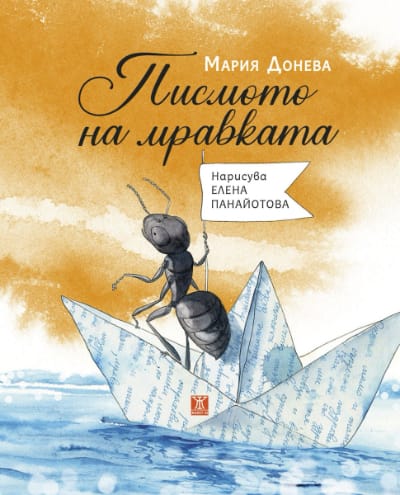
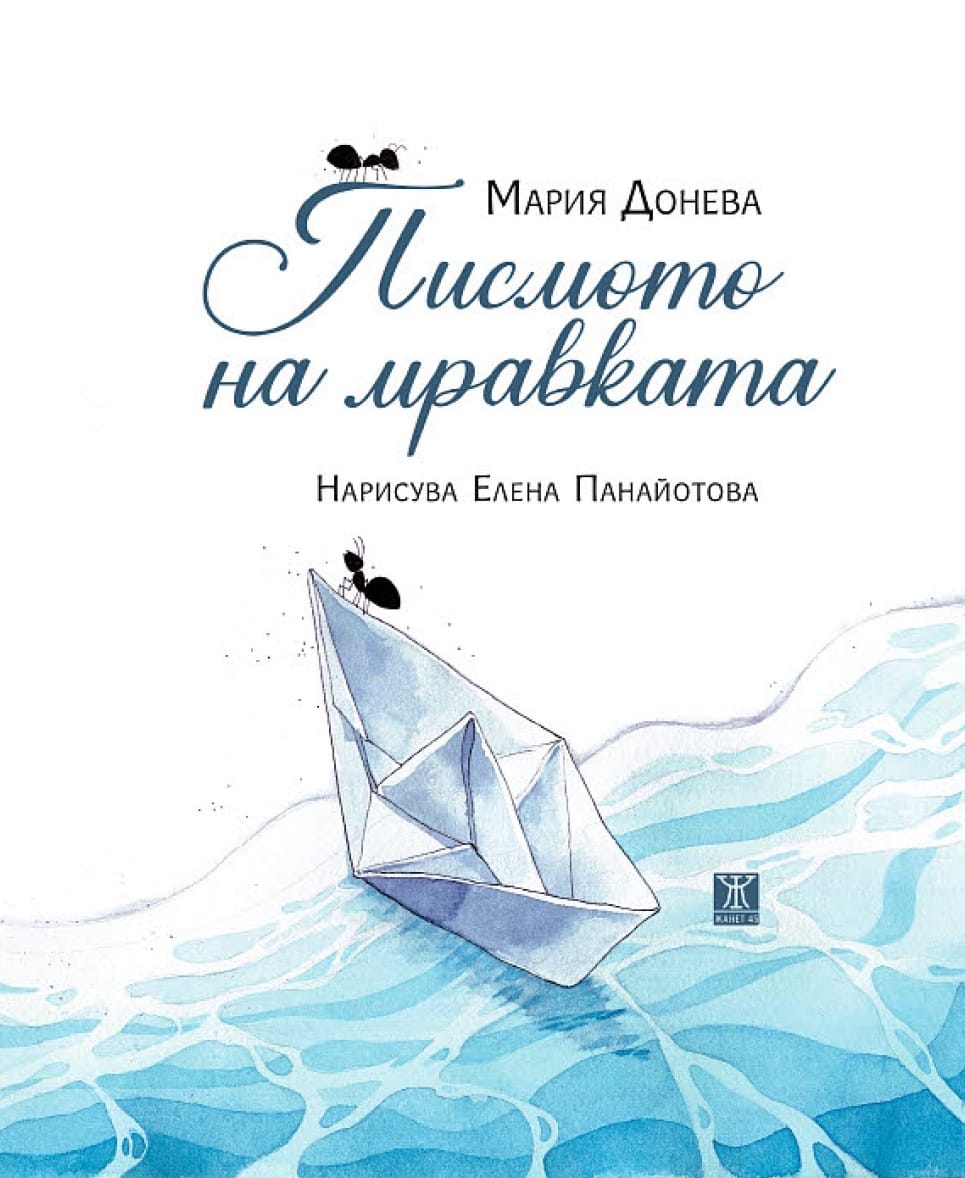
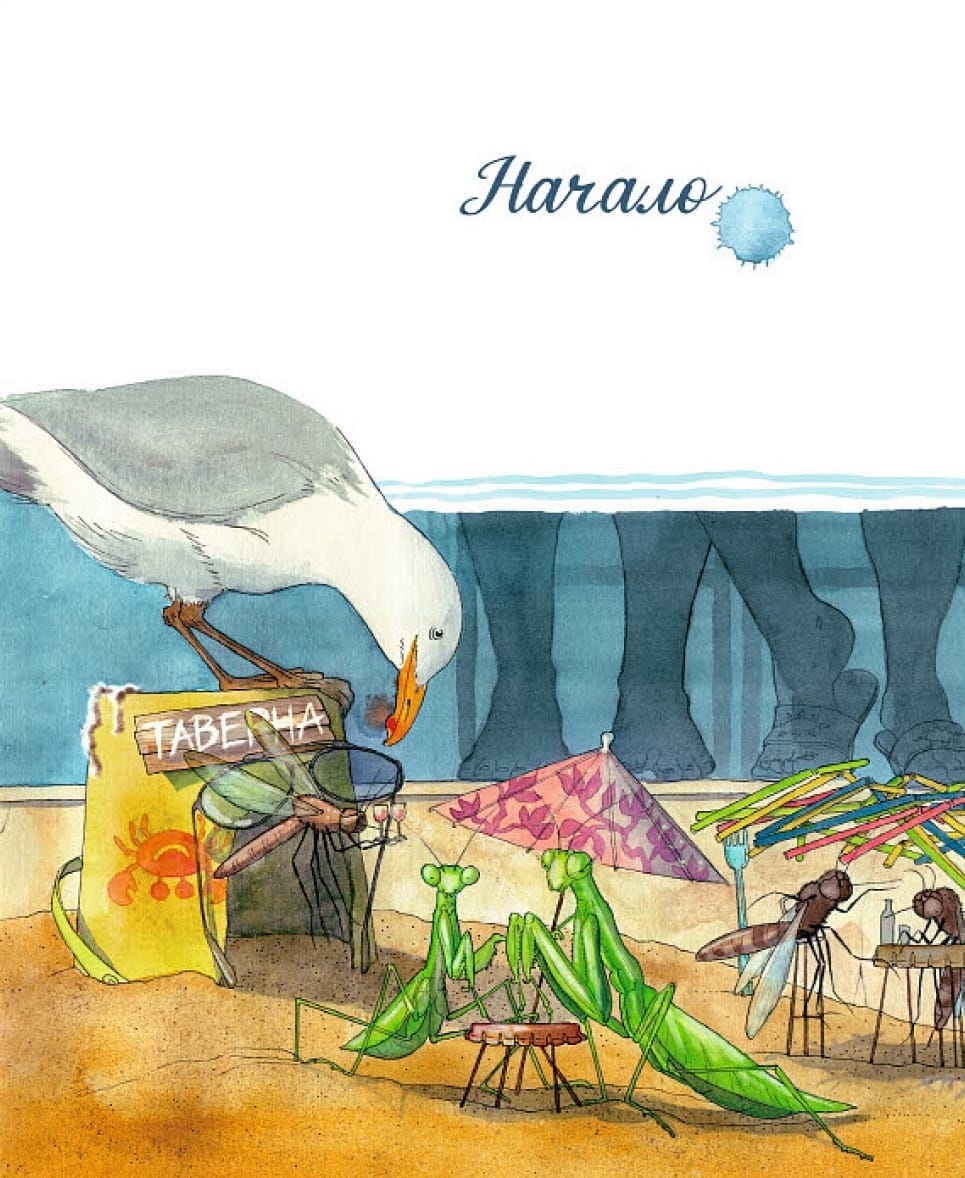
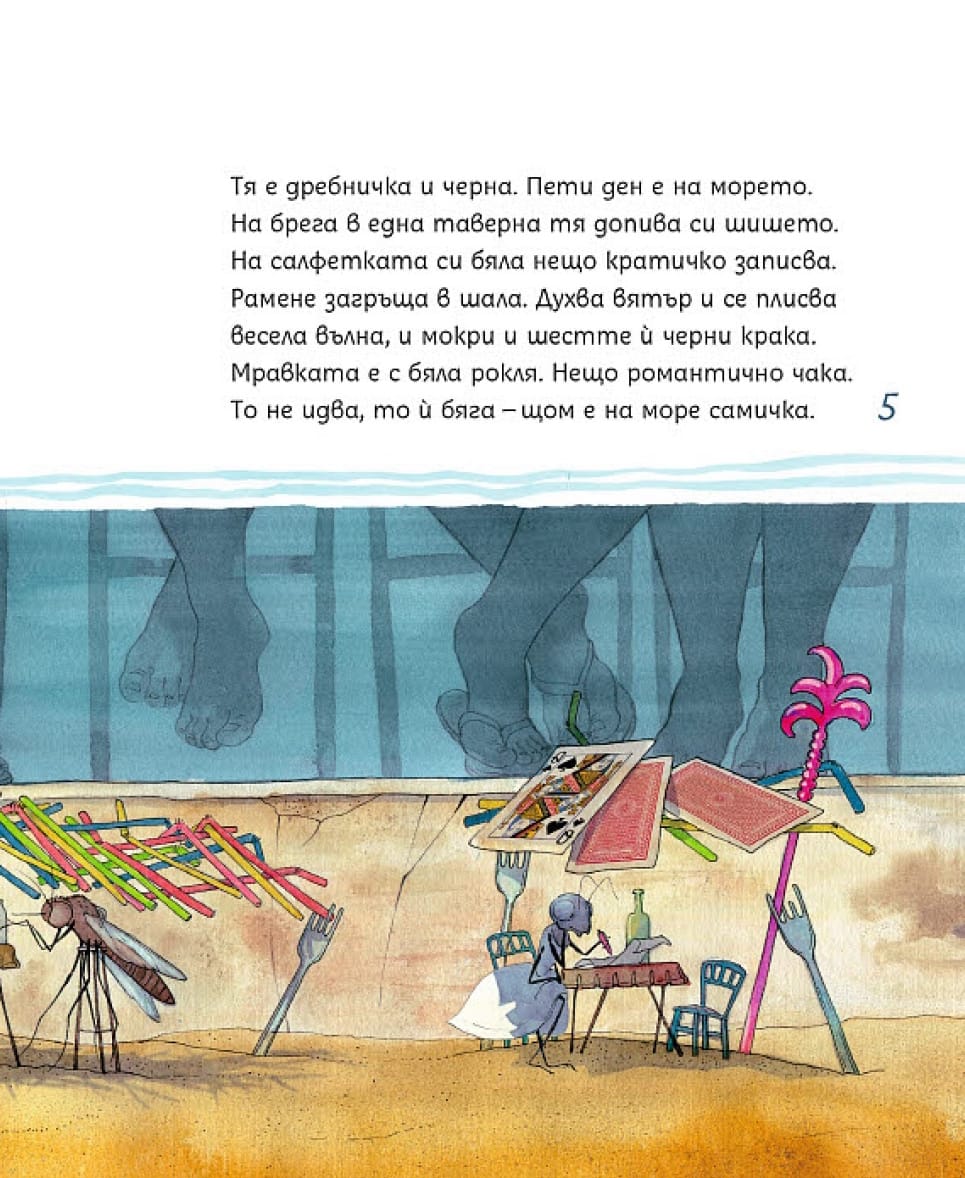
илюстрации Елена Панайотова, Пловдив: изд. „Жанет 45“, 2024
Да четеш Мария Донева е като да гледаш финала на „Ново кино Парадизо“, по-точно онази лента, която старият кинооператор Алфредо завещава на порасналия Салваторе, с всички цензурирани целувки, залепени една след друга. Взети заедно, те действат като филм от щастливи завършеци – разделените влюбени се срещат, неизказаната любов се осъществява, изгубеното се намира, устните се допират. Като наниза от начала в „Ако пътник в зимна нощ“, но наобратно.
В стихотворенията и поемите на Мария Донева сякаш има повече милост към читателя, че и към героите, отколкото литературата по принцип допуска; повече радост. Този последователен избор, книга след книга, ми се струва свързан с едно общително разбиране на връзката с читателя, с неговата потребност да види пред себе си и щадящите сценарии.
Умът ни е настроен да човърка катастрофичното, да го отбягва и пак да се връща при него. Да пишеш за възможността за щастие – и то така, че в нея да се разпознаят хора от всякакви разновидности и професии – не е никак лесно. Мария Донева го прави, като засилва цветовете, като изгражда собствен жанр. В него ролята на завръзката играе копнежът – дългият, с години неудовлетворен копнеж по нещо, което би изпълнило живота с живот.
Тук „Писмото на мравката“ се римува със „Заекът и неговата мечта“ и в известен смисъл дори с „Мишките отиват на опера“ – това са истории за вълнението, предвкусването и дългоочакваната среща. Основен елемент и у трите е достъпността на мечтаното, достъпност, която изглежда нереална само за героите. За читателя тя е двойно подсказана не само защото не е пътешествие до центъра на Земята – а любов между сродни, една среща с морето, една вечер в операта, – а и защото самата форма непрекъснато го подсказва. Звънкостта на стиха е щастливата история на думите – сдвоени в римите и ритъма, изглеждат смислово предопределени една за друга.
Впрочем това е особено при „Писмото на мравката“: тук в центъра е именно писането, писмото, и неговото пътешествие (и притеснение) е самата ос на сюжета. Писмото хвърля и елегантен мост към писмата у Валери Петров, с чийто звънък стих – и абсолютно спокойствие да говори за доброто – Мария Донева звучи вътрешно свързана.
A month ago at QConSF, we showcased how Netflix utilizes Metaflow to power a diverse set of ML and AI use cases, managing thousands of unique Metaflow flows. This followed a previous blog on the same topic. Many of these projects are under constant development by dedicated teams with their own business goals and development best practices, such as the system that supports our content decision makers, or the system that ranks which language subtitles are most valuable for a specific piece of content.
As a central ML and AI platform team, our role is to empower our partner teams with tools that maximize their productivity and effectiveness, while adapting to their specific needs (not the other way around). This has been a guiding design principle with Metaflow since its inception.
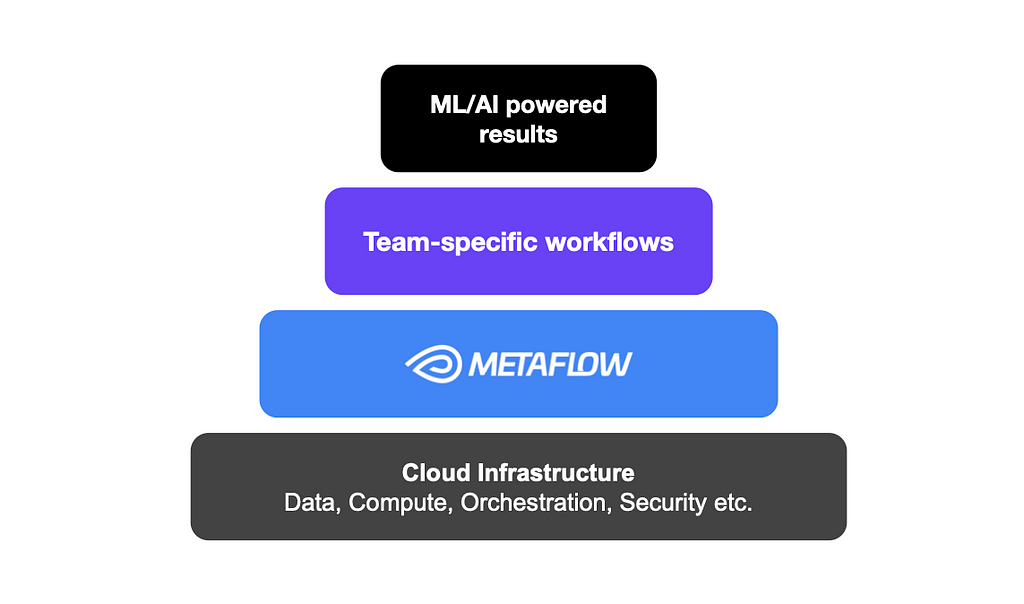
Metaflow infrastructure stack
Standing on the shoulders of our extensive cloud infrastructure, Metaflow facilitates easy access to data, compute, and production-grade workflow orchestration, as well as built-in best practices for common concerns such as collaboration, versioning, dependency management, and observability, which teams use to setup ML/AI experiments and systems that work for them. As a result, Metaflow users at Netflix have been able to run millions of experiments over the past few years without wasting time on low-level concerns.
A long standing FAQ: configurable flows
While Metaflow aims to be un-opinionated about some of the upper levels of the stack, some teams within Netflix have developed their own opinionated tooling. As part of Metaflow’s adaptation to their specific needs, we constantly try to understand what has been developed and, more importantly, what gaps these solutions are filling.
In some cases, we determine that the gap being addressed is very team specific, or too opinionated at too high a level in the stack, and we therefore decide to not develop it within Metaflow. In other cases, however, we realize that we can develop an underlying construct that aids in filling that gap. Note that even in that case, we do not always aim to completely fill the gap and instead focus on extracting a more general lower level concept that can be leveraged by that particular user but also by others. One such recurring pattern we noticed at Netflix is the need to deploy sets of closely related flows, often as part of a larger pipeline involving table creations, ETLs, and deployment jobs. Frequently, practitioners want to experiment with variants of these flows, testing new data, new parameterizations, or new algorithms, while keeping the overall structure of the flow or flows intact.
A natural solution is to make flows configurable using configuration files, so variants can be defined without changing the code. Thus far, there hasn’t been a built-in solution for configuring flows, so teams have built their bespoke solutions leveraging Metaflow’s JSON-typed Parameters, IncludeFile, and deploy-time Parameters or deploying their own home-grown solution (often with great pain). However, none of these solutions make it easy to configure all aspects of the flow’s behavior, decorators in particular.
Requests for a feature like Metaflow Config
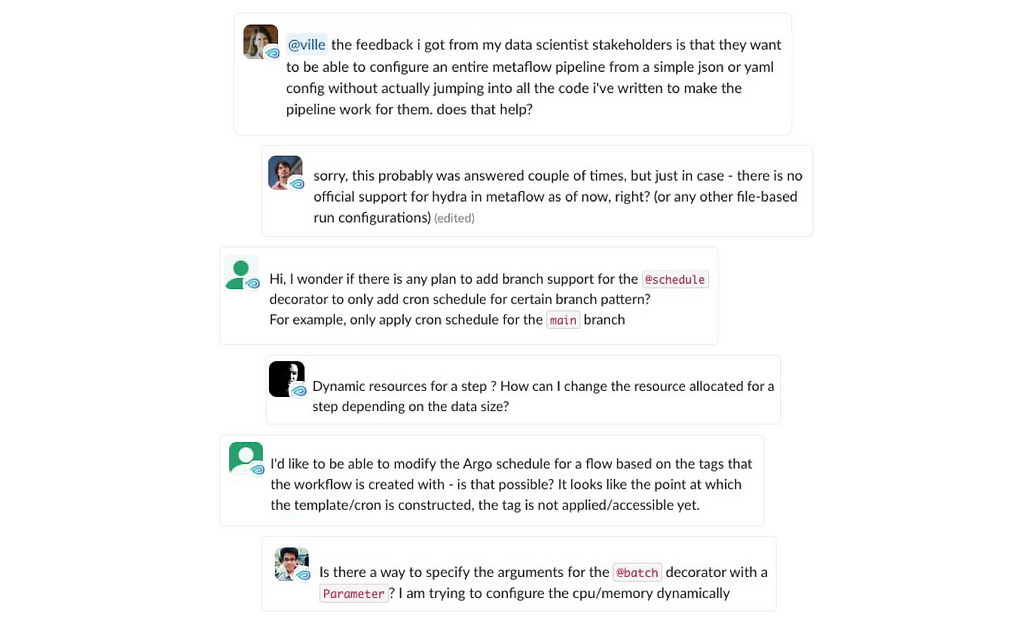
Outside Netflix, we have seen similar frequently asked questions on the Metaflow community Slack as shown in the user quotes above:
how can I adjust the @resource requirements, such as CPU or memory, without having to hardcode the values in my flows?
how to adjust the triggering @schedule programmatically, so our production and staging deployments can run at different cadences?
New in Metaflow: Configs!
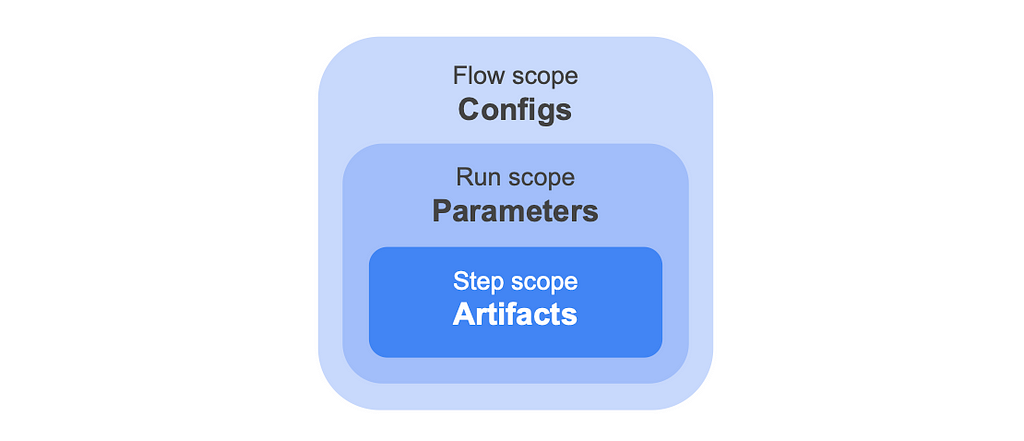
Today, to answer the FAQ, we introduce a new — small but mighty — feature in Metaflow: a Config object. Configs complement the existing Metaflow constructs of artifacts and Parameters, by allowing you to configure all aspects of the flow, decorators in particular, prior to any run starting. At the end of the day, artifacts, Parameters and Configs are all stored as artifacts by Metaflow but they differ in when they are persisted as shown in the diagram below:
Different data artifacts in Metaflow
Said another way:
An artifact is resolved and persisted to the datastore at the end of each task.
A parameter is resolved and persisted at the start of a run; it can therefore be modified up to that point. One common use case is to use triggers to pass values to a run right before executing. Parameters can only be used within your step code.
A config is resolved and persisted when the flow is deployed. When using a scheduler such as Argo Workflows, deployment happens when create’ing the flow. In the case of a local run, “deployment” happens just prior to the execution of the run — think of “deployment” as gathering all that is needed to run the flow. Unlike parameters, configs can be used more widely in your flow code, particularly, they can be used in step or flow level decorators as well as to set defaults for parameters. Configs can of course also be used within your flow.
As an example, you can specify a Config that reads a pleasantly human-readable configuration file, formatted as TOML. The Config specifies a triggering ‘@schedule’ and ‘@resource’ requirements, as well as application-specific parameters for this specific deployment:
[schedule]
cron = "0 * * * *"

[model]
optimizer = "adam"
learning_rate = 0.5

[resources]
cpu = 1
Using the newly released Metaflow 2.13, you can configure a flow with a Config like above, as demonstrated by this flow:
There is a lot going on in the code above, a few highlights:
you can refer to configs before they have been defined using ‘config_expr’.
you can define arbitrary parsers — using a string means the parser doesn’t even have to be present remotely!
From the developer’s point of view, Configs behave like dictionary-like artifacts. For convenience, they support the dot-syntax (when possible) for accessing keys, making it easy to access values in a nested configuration. You can also unpack the whole Config (or a subtree of it) with Python’s standard dictionary unpacking syntax, ‘**config’. The standard dictionary subscript notation is also available.
Since Configs turn into dictionary artifacts, they get versioned and persisted automatically as artifacts. You can access Configs of any past runs easily through the Client API. As a result, your data, models, code, Parameters, Configs, and execution environments are all stored as a consistent bundle — neatly organized in Metaflow namespaces — paving the way for easily reproducible, consistent, low-boilerplate, and now easily configurable experiments and robust production deployments.
More than a humble config file
While you can get far by accompanying your flow with a simple config file (stored in your favorite format, thanks to user-definable parsers), Configs unlock a number of advanced use cases. Consider these examples from the updated documentation:
You are not limited to using a single file: you can leverage a configuration manager like OmegaConf or Hydra to manage a hierarchy of cascading configuration files. You can also use a domain-specific tool for generating Configs, such as Netflix’s Metaboost which we cover below.
You can also generate configurations on the fly, e.g. fetch Configs from an external service, or inspect the execution environment, such as the current GIT branch, and include it as an extra piece of context in runs.
A major benefit of Config over previous more hacky solutions for configuring flows is that they work seamlessly with other features of Metaflow: you can run steps remotely and deploy flows to production, even when relying on custom parsers, without having to worry about packaging Configs or parsers manually or keeping Configs consistent across tasks. Configs also work with the Runner and Deployer.
The Hollywood principle: don’t call us, we’ll call you
When used in conjunction with a configuration manager like Hydra, Configs enable a pattern that is highly relevant for ML and AI use cases: orchestrating experiments over multiple configurations or sweeping over parameter spaces. While Metaflow has always supported sweeping over parameter grids easily using foreaches, it hasn’t been easily possible to alter the flow itself, e.g. to change @resources or @pypi/@conda dependencies for every experiment.
In a typical case, you trigger a Metaflow flow that consumes a configuration file, changing how a run behaves. With Hydra, you can invert the control: it is Hydra that decides what gets run based on a configuration file. Thanks to Metaflow’s new Runner and Deployer APIs, you can create a Hydra app that operates Metaflow programmatically — for instance, to deploy and execute hundreds of variants of a flow in a large-scale experiment.
Take a look at two interesting examples of this pattern in the documentation. As a teaser, this video shows Hydra orchestrating deployment of tens of Metaflow flows, each of which benchmarks PyTorch using a varying number of CPU cores and tensor sizes, updating a visualization of the results in real-time as the experiment progresses:
Metaboosting Metaflow — based on a true story
To give a motivating example of what configurations look like at Netflix in practice, let’s consider Metaboost, an internal Netflix CLI tool that helps ML practitioners manage, develop and execute their cross-platform projects, somewhat similar to the open-source Hydra discussed above but with specific integrations to the Netflix ecosystem. Metaboost is an example of an opinionated framework developed by a team already using Metaflow. In fact, a part of the inspiration for introducing Configs in Metaflow came from this very use case.
Metaboost serves as a single interface to three different internal platforms at Netflix that manage ETL/Workflows (Maestro), Machine Learning Pipelines (Metaflow) and Data Warehouse Tables (Kragle). In this context, having a single configuration system to manage a ML project holistically gives users increased project coherence and decreased project risk.
Configuration in Metaboost
Ease of configuration and templatizing are core values of Metaboost. Templatizing in Metaboost is achieved through the concept of bindings, wherein we can bind a Metaflow pipeline to an arbitrary label, and then create a corresponding bespoke configuration for that label. The binding-connected configuration is then merged into a global set of configurations containing such information as GIT repository, branch, etc. Binding a Metaflow, will also signal to Metaboost that it should instantiate the Metaflow flow once per binding into our orchestration cluster.
Imagine a ML practitioner on the Netflix Content ML team, sourcing features from hundreds of columns in our data warehouse, and creating a multitude of models against a growing suite of metrics. When a brand new content metric comes along, with Metaboost, the first version of the metric’s predictive model can easily be created by simply swapping the target column against which the model is trained.
Subsequent versions of the model will result from experimenting with hyper parameters, tweaking feature engineering, or conducting feature diets. Metaboost’s bindings, and their integration with Metaflow Configs, can be leveraged to scale the number of experiments as fast as a scientist can create experiment based configurations.
Scaling experiments with Metaboost bindings — backed by Metaflow Config
Consider a Metaboost ML project named `demo` that creates and loads data to custom tables (ETL managed by Maestro), and then trains a simple model on this data (ML Pipeline managed by Metaflow). The project structure of this repository might look like the following:
Metaboost will merge each experiment configuration (*.EXP*.yaml) into the global configuration (settings.configuration.yaml) individually at Metaboost command initialization. Let’s take a look at how Metaboost combines these configurations with a Metaboost command:
(venv-demo) ~/projects/metaboost-demo [branch=demoX]
$ metaboost metaflow settings show --yaml-path=configuration

binding=EXP_01:
model:                     -> defined in setting.configuration.yaml (global)
  fit_intercept: true
conda:                     -> defined in setting.configuration.yaml (global)
  numpy: 1.22.4
  "scikit-learn": 1.4.0
target_column: metricA     -> defined in setting.configuration.EXP_01.yaml
features:                  -> defined in setting.configuration.EXP_01.yaml
- runtime
- content_type
- top_billed_talent

binding=EXP_02:
model:                     -> defined in setting.configuration.yaml (global)
  fit_intercept: true
conda:                     -> defined in setting.configuration.yaml (global)
  numpy: 1.22.4
  "scikit-learn": 1.4.0
target_column: metricA     -> defined in setting.configuration.EXP_02.yaml
features:                  -> defined in setting.configuration.EXP_02.yaml
- runtime
- director
- box_office
Metaboost understands it should deploy/run two independent instances of training.py — one for the EXP_01 binding and one for the EXP_02 binding. You can also see that Metaboost is aware that the tables and ETL workflows are not bound, and should only be deployed once. These details of which artifacts to bind and which to leave unbound are encoded in the project’s top-level metaboost.yaml file.
(venv-demo) ~/projects/metaboost-demo [branch=demoX] $ metaboost project list
Below is a simple Metaflow pipeline that fetches data, executes feature engineering, and trains a LinearRegression model. The work to integrate Metaboost Settings into a user’s Metaflow pipeline (implemented using Metaflow Configs) is as easy as adding a single mix-in to the FlowSpec definition:
from metaflow import FlowSpec, Parameter, conda_base, step from custom.data import feature_engineer, get_data from metaflow.metaboost import MetaboostSettings
@step def start(self): # get show_settings() for free with the mixin # and get convenient debugging info self.show_settings(exclude_patterns=["artifact*", "system*"])
self.next(self.get_features)
@step def get_features(self): # feature engineers on our extracted data self.fe_df = feature_engineer( # loads data from our ETL pipeline data=get_data(prediction_date=self.prediction_date), features=self.settings.configuration.features + [self.settings.configuration.target_column] )
self.next(self.train)
@step def train(self): from sklearn.linear_model import LinearRegression
The Metaflow Config is added to the FlowSpec by mixing in the MetaboostSettings class. Referencing a configuration value is as easy as using the dot syntax to drill into whichever parameter you’d like.
Finally let’s take a look at the output from our sample Metaflow above. We execute experiment EXP_01 with
metaboost metaflow run --binding=EXP_01
which upon execution will merge the configurations into a single settings file (shown previously) and serialize it as a yaml file to the .metaboost/settings/compiled/ directory.
You can see the actual command and args that were sub-processed in the Metaboost Execution section below. Please note the –config argument pointing to the serialized yaml file, and then subsequently accessible via self.settings. Also note the convenient printing of configuration values to stdout during the start step using a mixed in function named show_settings().
(venv-demo) ~/projects/metaboost-demo [branch=demoX] $ metaboost metaflow run --binding=EXP_01
Metaflow 2.12.39+nflxfastdata(2.13.5);nflx(2.13.5);metaboost(0.0.27) executing DemoTraining for user:dcasler Validating your flow... The graph looks good! Bootstrapping Conda environment... (this could take a few minutes) All packages already cached in s3. All environments already cached in s3.
Workflow starting (run-id 50), see it in the UI at https://metaflowui.prod.netflix.net/DemoTraining/50
[50/get_features/251640840] Task is starting. [50/get_features/251640840] Task finished successfully.
[50/train/251640854] Task is starting. [50/train/251640854] Fit slope: 0.4702672504331096 [50/train/251640854] Fit intercept: -6.247919678070083 [50/train/251640854] Task finished successfully.
[50/end/251640868] Task is starting. [50/end/251640868] Task finished successfully.
Done! See the run in the UI at https://metaflowui.prod.netflix.net/DemoTraining/50
Takeaways
Metaboost is an integration tool that aims to ease the project development, management and execution burden of ML projects at Netflix. It employs a configuration system that combines git based parameters, global configurations and arbitrarily bound configuration files for use during execution against internal Netflix platforms.
Integrating this configuration system with the new Config in Metaflow is incredibly simple (by design), only requiring users to add a mix-in class to their FlowSpec — similar to this example in Metaflow documentation — and then reference the configuration values in steps or decorators. The example above templatizes a training Metaflow for the sake of experimentation, but users could just as easily use bindings/configs to templatize their flows across target metrics, business initiatives or any other arbitrary lines of work.
Try it at home
It couldn’t be easier to get started with Configs! Just
If you have any questions or feedback about Config (or other Metaflow features), you can reach out to us at the Metaflow community Slack.
Acknowledgments
We would like to thank Outerbounds for their collaboration on this feature; for rigorously testing it and developing a repository of examples to showcase some of the possibilities offered by this feature.
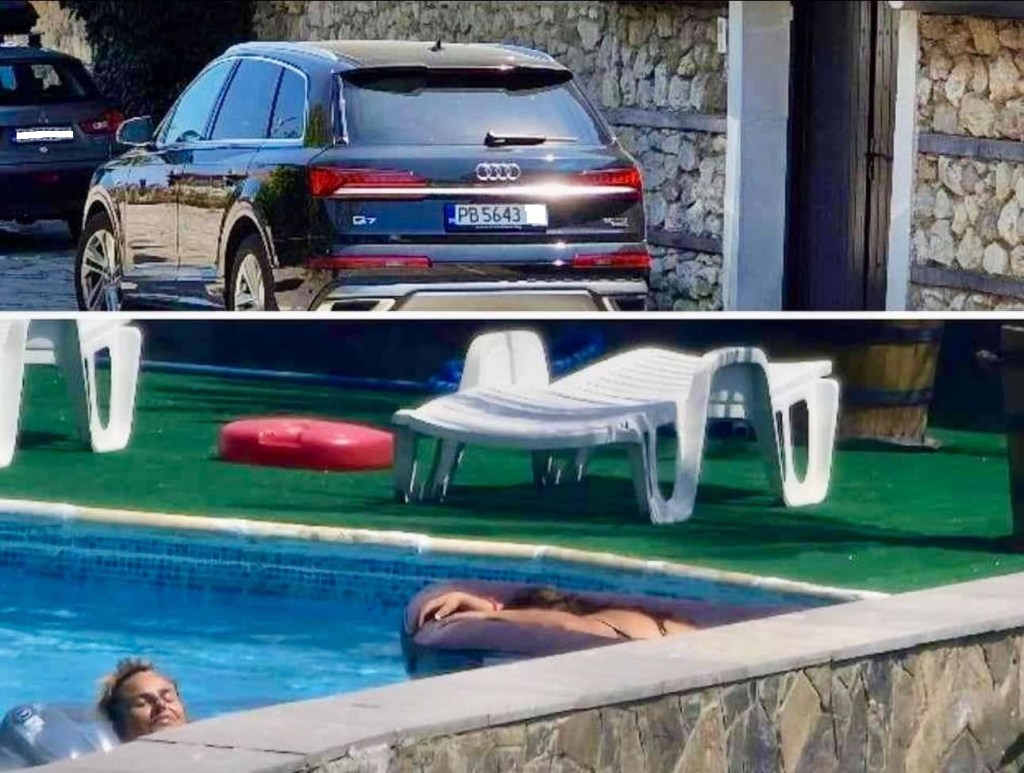
Кметът на третия по големина град на Българското Черноморие, Поморие – Иван Алексиев, е засечен заедно със семейството си да консумира луксозен живот чрез чужда собственост – частна и общинска.…
We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce the successful completion of our first ever Protected B High Value Assets (PBHVA) assessment with 149 assessed services and features. Completion of this assessment effective October 4, 2024, makes AWS the first cloud service provider (CSP) in Canada to meet this high security bar and provide assurance to our valued customers. This assessment also re-affirms our commitment to helping public and commercial customers achieve and maintain the highest-grade security standard for workloads with increased sensitivity.
What is the PBHVA assessment and why is it important?
The Protected B High Value Asset (PBHVA) overlay seeks to enhance the integrity and availability of customer organizational workloads that are considered to have an increased level of sensitivity. These are systems that the Government of Canada (GC) and its service providers use to support delivery of services at a national scale or that are determined to be significant for handling sensitive information. The overlay is a set of 117 controls from the ITSG-33 security control catalogue (baselined against NIST 800-53), which augments the security safeguards to enhance integrity and availability.
As of October 4, 2024, there are a total of 149 AWS services and features that were assessed by the Canadian Centre for Cyber Security (CCCS) under PBHVA assessment criteria. The assessment covers services and features that are available in both the Canada (Central) and Canada West (Calgary) AWS Regions.
How can you access the assessment?
The summary assessment is available through AWS Artifact. You can also learn more about the PBHVA assessment on our AWS PBHVA webpage.
AWS strives to continuously bring services into scope of its compliance programs to help you meet your architectural and regulatory needs. Please reach out to your AWS account team if you have questions or feedback about the PBHVA assessment.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
As we preannounced at AWS re:Invent 2024, you can now use Stable Diffusion 3.5 Large in Amazon Bedrock to generate high-quality images from text descriptions in a wide range of styles to accelerate the creation of concept art, visual effects, and detailed product imagery for customers in media, gaming, advertising, and retail.
In October 2024, Stability AI introduced Stable Diffusion 3.5 Large, the most powerful model in the Stable Diffusion family at 8.1 billion parameters trained on Amazon SageMaker HyperPod, with superior quality and prompt adherence. Stable Diffusion 3.5 Large can accelerate storyboarding, concept art creation, and rapid prototyping of visual effects. You can quickly generate high-quality 1-megapixel images for campaigns, social media posts, and advertisements, saving time and resources while maintaining creative control.
Versatile Styles – You can generate images in a wide range of styles and aesthetics, including 3-dimentional, photography, painting, line art, and virtually any visual style you can imagine.
Prompt Adherence – You can use Stable Diffusion 3.5 Large’s advanced prompt adherence to closely follow your text prompts, making it a top choice for efficient, high-quality performance.
Diverse Outputs – You can create images representative of the diverse world around you, featuring people with different skin tones and features, without the need for extensive prompting.
Today, Stable Image Ultra in Amazon Bedrock has been updated to include Stable Diffusion 3.5 Large in the model’s underlying architecture. Stable Image Ultra, powered by Stability AI’s most advanced models, including Stable Diffusion 3.5, sets a new standard in image generation. It excels in typography, intricate compositions, dynamic lighting, vibrant colors, and artistic cohesion.
With the latest update of Stable Diffusion models in Amazon Bedrock, you have a broader set of solutions to boost your creativity and accelerate image generation workflows.
Get started with Stable Diffusion 3.5 Large in Amazon Bedrock Before getting started, if you are new to using Stability AI models, go to the Amazon Bedrock console and choose Model access on the bottom left pane. To access the latest Stability AI models, request access for Stable Diffusion 3.5 Large in Stability AI.
To test the Stability AI models in Amazon Bedrock, choose Image/Video under Playgrounds in the left menu pane. Then choose Select model and select Stability AI as the category and Stable Diffusion 3.5 Large as the model.
You can generate an image with your prompt. Here is a sample prompt to generate the image:
High-energy street scene in a neon-lit Tokyo alley at night, where steam rises from food carts, and colorful neon signs illuminate the rain-slicked pavement.
By choosing View API request, you can also access the model using code examples in the AWS Command Line Interface (AWS CLI) and AWS SDKs. You can use stability.sd3-5-large-v1:0 as the model ID.
To get the image with a single command, I write the output JSON file to standard output and use the jq tool to extract the encoded image so that it can be decoded on the fly. The output is written in the img.png file.
Here is a sample of the AWS CLI command:
$ aws bedrock-runtime invoke-model \
   --model-id stability.sd3-5-large-v1:0 \
   --body "{\"text_prompts\":[{\"text\":\"High-energy street scene in a neon-lit Tokyo alley at night, where steam rises from food carts, and colorful neon signs illuminate the rain-slicked pavement.\",\"weight\":1}],\"cfg_scale\":0,\"steps\":10,\"seed\":0,\"width\":1024,\"height\":1024,\"samples\":1}" \
   --cli-binary-format raw-in-base64-out \
   --region us-west-2 \
/dev/stdout | jq -r '.images[0]' | base64 --decode > img.jpg
Here’s how you can use Stable Image Ultra 1.1 to include Stable Diffusion 3.5 Large in the model’s underlying architecture with the AWS SDK for Python (Boto3). This simple application interactively asks for a text-to-image prompt and then calls Amazon Bedrock to generate the image with stability.stable-image-ultra-v1:1 as the model ID.
import base64
import boto3
import json
import os

MODEL_ID = "stability.stable-image-ultra-v1:1"

bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-west-2")

print("Enter a prompt for the text-to-image model:")
prompt = input()

body = {
    "prompt": prompt,
    "mode": "text-to-image"
}
response = bedrock_runtime.invoke_model(modelId=MODEL_ID, body=json.dumps(body))

model_response = json.loads(response["body"].read())

base64_image_data = model_response["images"][0]

i, output_dir = 1, "output"
if not os.path.exists(output_dir):
    os.makedirs(output_dir)
while os.path.exists(os.path.join(output_dir, f"img_{i}.png")):
    i += 1

image_data = base64.b64decode(base64_image_data)

image_path = os.path.join(output_dir, f"img_{i}.png")
with open(image_path, "wb") as file:
    file.write(image_data)

print(f"The generated image has been saved to {image_path}")
The application writes the resulting image in an output directory that is created if not present. To not overwrite existing files, the code checks for existing files to find the first file name available with the img_<number>.png format.
To learn more, visit the Invoke API examples using AWS SDKs to build your applications to generate an image using various programming languages.
Interesting examples Here are a few images created with Stable Diffusion 3.5 Large.
Prompt: Full-body university students working on a tech project with the words Stable Diffusion 3.5 in Amazon Bedrock, cheerful cursive typography font in the foreground.
Prompt: Photo of three potions: the first potion is blue with the label "MANA", the second potion is red with the label "HEALTH", the third potion is green with the label "POISON". Old apothecary.
Prompt: Photography, pink rose flowers in the twilight, glowing, tile houses in the background.
Prompt: 3D animation scene of an adventurer traveling the world with his pet dog.
Amazon Web Services (AWS) is pleased to announce enhancements to our Payment Card Industry (PCI) compliance portfolio, further empowering AWS customers to build and manage secure, compliant payment environments with greater ease and flexibility.
PCI Data Security Standard (DSS): Our latest AWS PCI DSS v4 Attestation of Compliance (AOC) is now available and includes six additional AWS services:
This expansion allows you to use these services while maintaining PCI DSS compliance, enabling innovation without compromising security. You can see the full list of services at AWS Services in Scope by Compliance Program.
AWS CloudHSM: Manage your encryption keys on FIPS 140-2 Level 3 certified hardware in your own virtual private cloud (VPC), with a dedicated, single-tenant hardware security module (HSM) solution.
AWS Payment Cryptography: Use payment HSMs that are PCI PIN Transaction Security (PTS) HSM certified and fully managed by AWS, with PCI PIN and point-to-point encryption (P2PE)–compliant key management.
These refreshed attestations offer you greater flexibility in deploying regulated workloads while significantly reducing your compliance overhead. You can access the PCI DSS and PIN AOC reports through AWS Artifact. This self-service portal provides on-demand access to AWS compliance reports, streamlining your audit processes.
To learn more about our PCI programs and other compliance and security programs, see the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
If you’re responsible for backup operations, you’ve probably heard this question more times than you can count. While the answer should be a simple “yes,” staying on top of backup activities often involves checking multiple systems, reviewing logs, and maintaining manual tracking processes.
Today, I’m sharing five ways you can implement Backblaze Event Notifications into your data protection strategy to keep you and your team informed. If you’re interested in Event Notifications for other use cases, check out our posts for media production and application workflows.
Event Notifications for IT backup: Simplified automation
Event Notifications monitors your B2 Cloud Storage buckets for data changes that you designate—like completed backups, file deletions, or policy violations—and delivers real-time alerts where you want them. These alerts can trigger automated actions in any system that accepts webhooks, from PagerDuty to Zendesk to Slack channels and more.
Think of it as your storage system’s notification service: instead of discovering changes during routine recovery verification checks, you get instant awareness when something happens to the data in your buckets.
What are webhooks?
Webhooks, if you’re not familiar, are a way for applications to communicate with each other by sending data automatically based on specific events, e.g., HTTP POST requests with a JSON payload. What sets Backblaze Event Notifications apart is that it works with any service that accepts webhooks. This means you can integrate backup monitoring into your existing tools and processes, rather than being locked into specific vendors’ ecosystems.
5 ways to stay in the know with your backup strategy
Here are specific, practical ways you can take advantage of Event Notifications for immediate benefits to your backup and archive workflows.
1. Backup verification and reporting
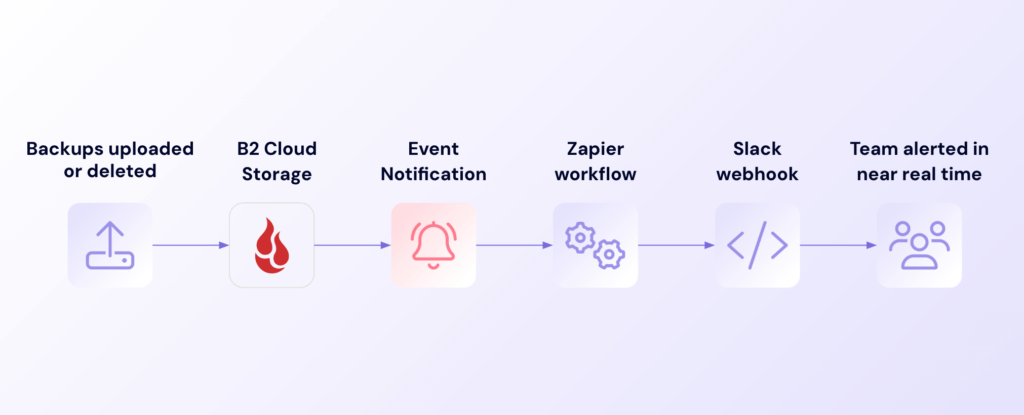
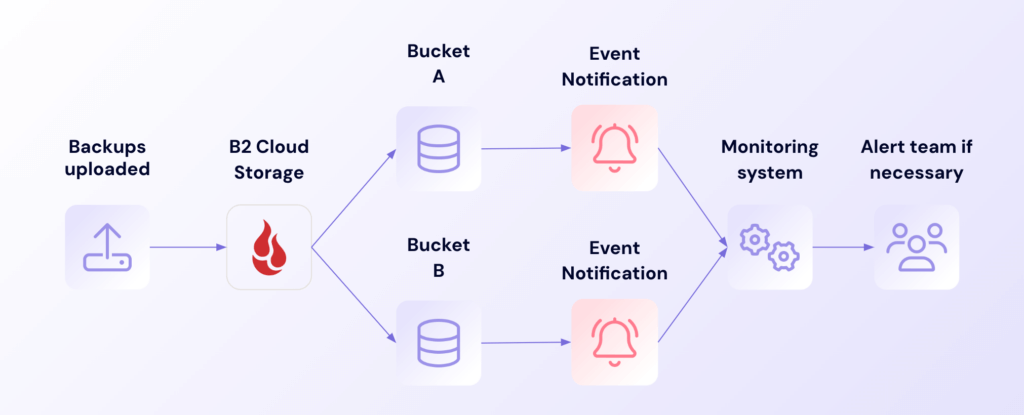
When your backup software writes files to B2 Cloud Storage, Event Notifications helps verify successful completion of backup jobs. Each time a backup file lands in a bucket, you’ll receive a notification with key details like file size, timestamp, and backup job name. By feeding this data directly into communication tools like Slack, you can maintain comprehensive logs of backup activity without manual checks.
Backup monitoring workflow
Gone are the days of discovering backup issues hours or days later during routine reviews—you’ll know exactly when backups are uploaded. Teams can configure custom alerts for backup size thresholds, receive immediate confirmation of successful backups, and, with the help of Zapier, you can enable an alert when Event Notifications did not trigger, indicating a backup was not uploaded during a specified window.
2. Security and compliance monitoring
Event Notifications can help protect your backup data from unauthorized changes. Security teams can establish automated alerts for suspicious activities like mass deletions or modifications. These alerts integrate with your existing security information and event management (SIEM) systems to provide unified threat monitoring.
Security alert workflow
Beyond threat detection, Event Notifications enables preemptive policy enforcement. Teams can configure automatic notifications that guide employees when their actions might conflict with backup policies—like modifying file names, moving files, or even deletion. For persistent policy conflicts, managers can receive automated escalation alerts to address potential training needs or process gaps. This systematic approach helps maintain backup integrity through education and awareness before issues occur, rather than just detecting violations after the fact.
3. Storage management automation
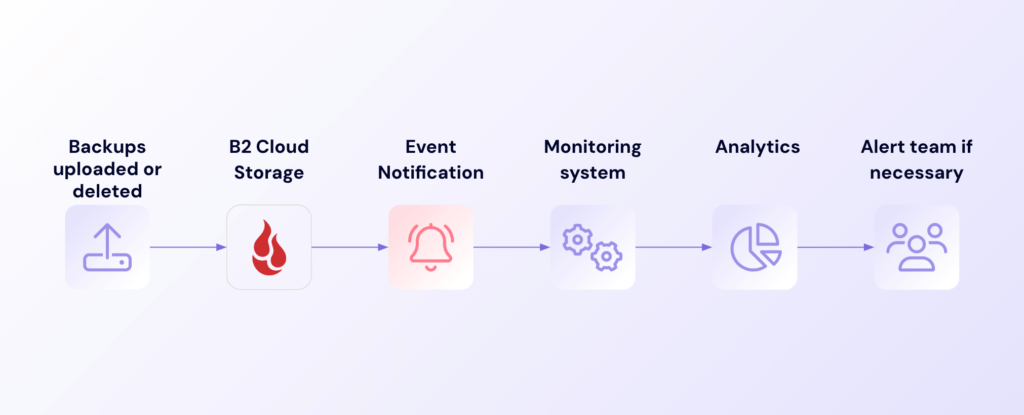
Storage management becomes more efficient when Event Notifications feeds activity data directly to your management tools. As files are uploaded to and removed from your buckets over time, Event Notifications provides valuable data that helps you analyze storage utilization trends and backup data growth patterns.
Data usage monitoring workflow
This constant flow of information empowers teams to anticipate capacity needs and optimize resource allocation. Moving from reactive to proactive storage management helps control costs by notifying you when backups become larger on average.
4. Cross-bucket backup monitoring
Organizations using Cloud Replication or managing backups across multiple buckets gain valuable oversight through Event Notifications. This capability tracks file replication between regions and monitors backup activity across your entire footprint, giving you a comprehensive view of your distributed backup strategy. Teams can spot replication delays or issues immediately, rather than waiting for scheduled status checks.
Cloud Replication notification workflow
Understanding how data moves and grows across different locations ensures your distributed backup strategy performs as designed. Event Notifications makes it possible to track successful replications, monitor consistency between primary and replica buckets, and receive immediate alerts about any issues. This visibility is especially valuable for organizations maintaining geographic redundancy or managing complex multi-site backup strategies.
5. Integration with IT workflows
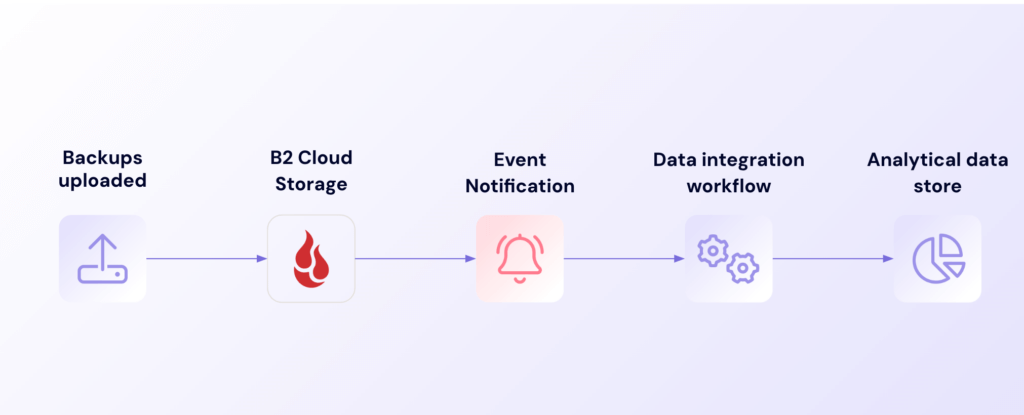
Event Notifications connects seamlessly with existing IT tools and processes through standard webhooks. Backup events can automatically flow into ticketing systems like Jira Service Management, monitoring dashboards like Grafana, or team communication channels like Microsoft Teams and Mattermost. This integration means teams can manage backup operations through familiar tools and processes, without needing to constantly switch between different interfaces or learn new systems.
Data integration workflow
The result is streamlined operations without the need for separate backup monitoring systems, ensuring backup activities receive proper attention within normal IT procedures. Teams can create ServiceNow tickets for failed backups, update Jira boards with backup status, or send notifications to Teams channels—all automatically and in real-time.
Why Event Notifications makes sense for backup teams
Managing backup operations has traditionally meant juggling multiple monitoring tools and hoping you catch issues before they impact recovery capabilities. Event Notifications transforms this approach by providing:
Automated awareness: Replace manual checks with instant visibility into bucket changes.
Enhanced security: Track backup data access and modifications as they happen.
Simplified monitoring: Feed backup activity data directly to your management tools.
Better operations: Free up time to focus on improving backup strategies rather than monitoring them.
Flexible integration: Adapt backup monitoring to fit your existing processes, not the other way around.
How it works with your environment
Unlike traditional backup monitoring solutions that often require specific software for notification handling, Event Notifications works with any service that accepts webhooks. This fundamental difference means you aren’t locked into specific vendors’ ecosystems or forced to use particular monitoring tools.
Event Notifications is designed for reliability with at-least-once delivery, ensuring critical backup events are never missed. This reliability is especially important for teams building automated workflows that require consistency and transparency in their backup monitoring.
The pricing model is straightforward and predictable: Backblaze B2 Reserve customers receive unlimited notifications at no additional cost, while pay-as-you-go customers get 2,500 notifications free each day and pay just $0.004 per 10,000 additional calls. This transparent pricing applies regardless of which services you’re connecting to, enabling teams to build comprehensive backup monitoring without worrying about unpredictable costs.
Ready to automate your backup monitoring?
If you’re working with a Backblaze account manager, Event Notifications are already enabled—just ask them for setup guidance. Other existing customers can contact our Support team to request access.
New to Backblaze? Contact our Sales team to learn how Event Notifications can strengthen your backup operations. Once enabled, visit the Event Notifications section in your B2 Cloud Storage buckets to configure your alerts. For detailed setup instructions and best practices, check out our Event Notifications documentation.
We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that the Fall 2024 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover 183 services over the 12-month period from October 1, 2023 to September 30, 2024, so that customers have a full year of assurance with the reports. These reports demonstrate our continuous commitment to adhere to the heightened expectations for cloud service providers.
Going forward, we will issue SOC reports covering a 12-month period each quarter as follows:
AWS strives to continuously bring services into the scope of its compliance programs to help you meet your architectural and regulatory needs. If you have questions or feedback about SOC compliance, reach out to your AWS account team.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.