Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=qTO8VJPwgpM
Ada Computer Science: What have we learnt so far
Post Syndicated from Ben Durbin original https://www.raspberrypi.org/blog/ada-computer-science-what-have-we-learnt-so-far/
It’s been over a year since we launched Ada Computer Science, and we continue to see the numbers of students and teachers using the platform all around the world grow. Our recent year in review shared some of the key developments we’ve made since launching, many of which are a direct result of feedback from our community.
Today, we are publishing an impact report that includes some of this feedback, along with what users are saying about the impact Ada Computer Science is having.
Evaluating Ada Computer Science
Ada Computer Science is a free learning platform for computer science students and teachers. It provides high-quality, online learning materials to use in the classroom, for homework, and for revision. Our experienced team has created resources that cover every topic in the leading GCSE and A level computer science specifications.
From May to July 2024, we invited users to provide feedback via an online survey, and we got responses from 163 students and 27 teachers. To explore the feedback further, we also conducted in-depth interviews with three computer science teachers in September 2024.
How is Ada being used?
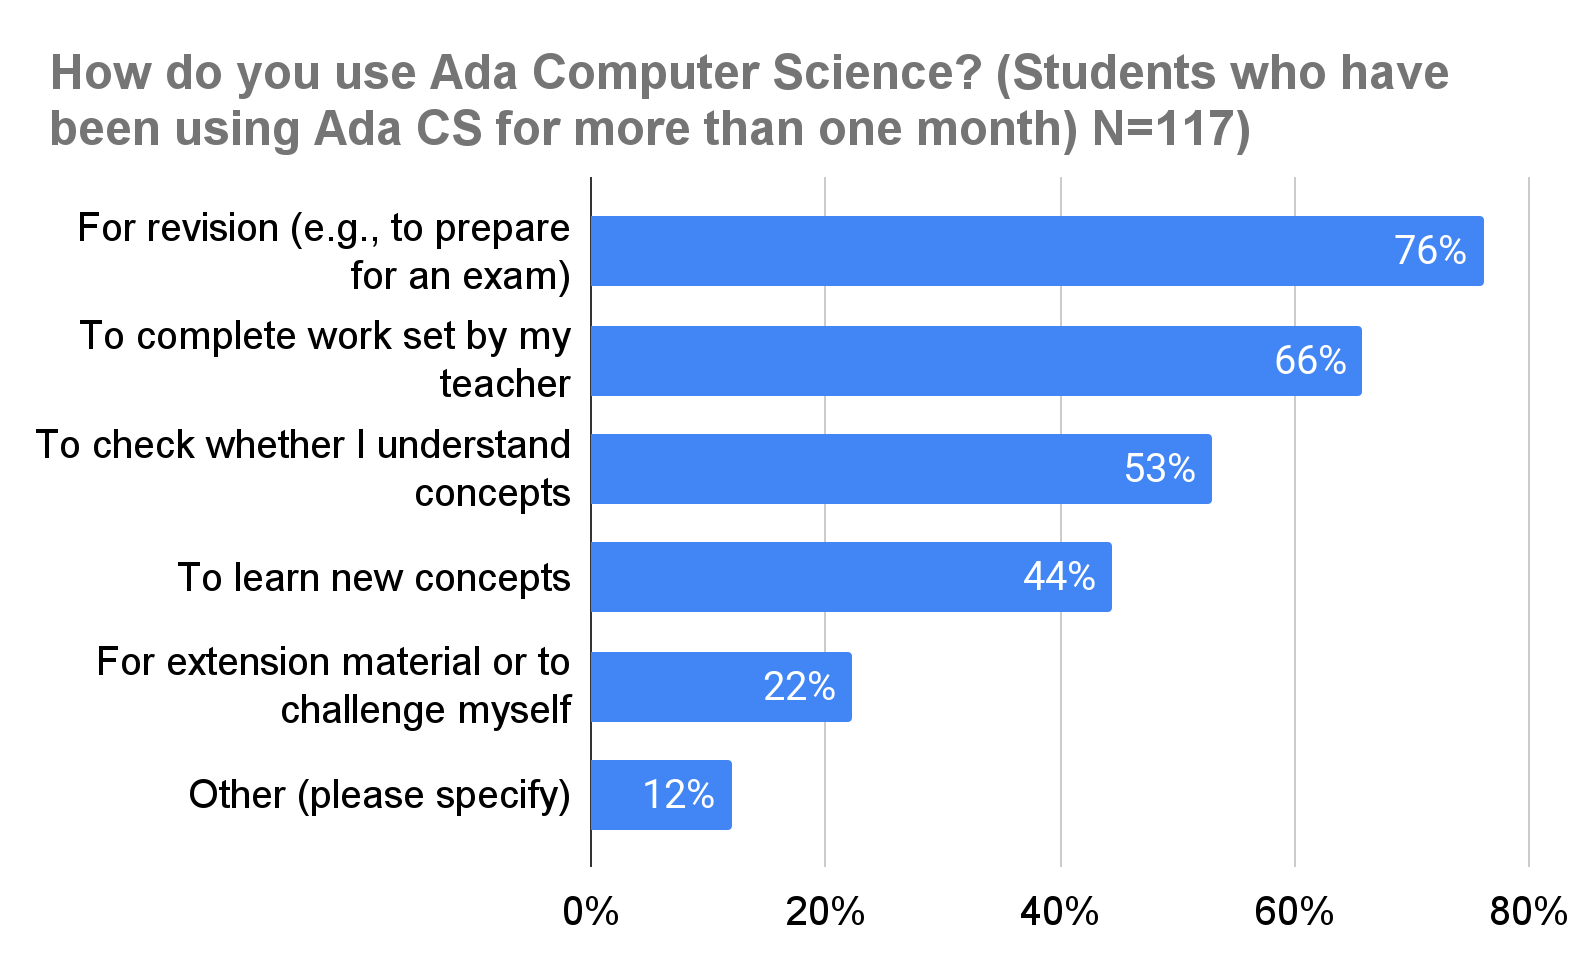
The most common ways students use Ada Computer Science — as reported by more than two thirds of respondents — is for revision and/or to complete work set by their teacher. Similarly, teachers most commonly said that they direct students to use Ada outside the classroom.
“I recommend my students use Ada Computer Science as their main textbook.” — Teacher
What is users’ experience of using Ada?
Most respondents agreed or strongly agreed that Ada is useful for learning (82%) and high quality (79%).
“Ada Computer Science has been very effective for independent revision, I like how it provides hints and pointers if you answer a question incorrectly.” — Student
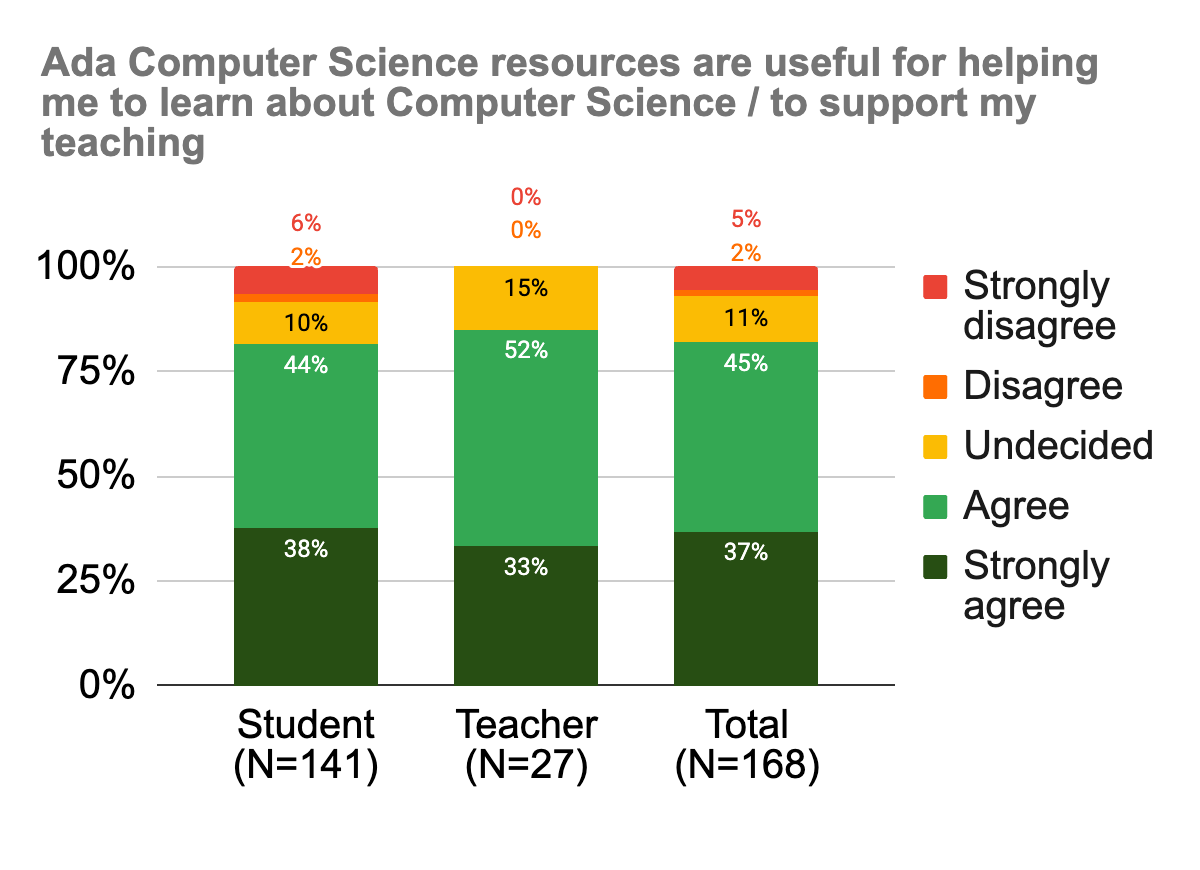
Ada users were generally positive about their overall experience of the platform and using it to find the information they were looking for.
“Ada is one of the best for hitting the nail on the head. They’ve really got it in tune with the depth that exam boards want.” — Ian Robinson, computer science teacher (St Alban’s Catholic High School, UK)
What impact is Ada having?
Around half of the teachers agreed that Ada had reduced their workload and/or increased their subject knowledge. Across all respondents, teachers estimated that the average weekly time saving was 1 hour 8 minutes.
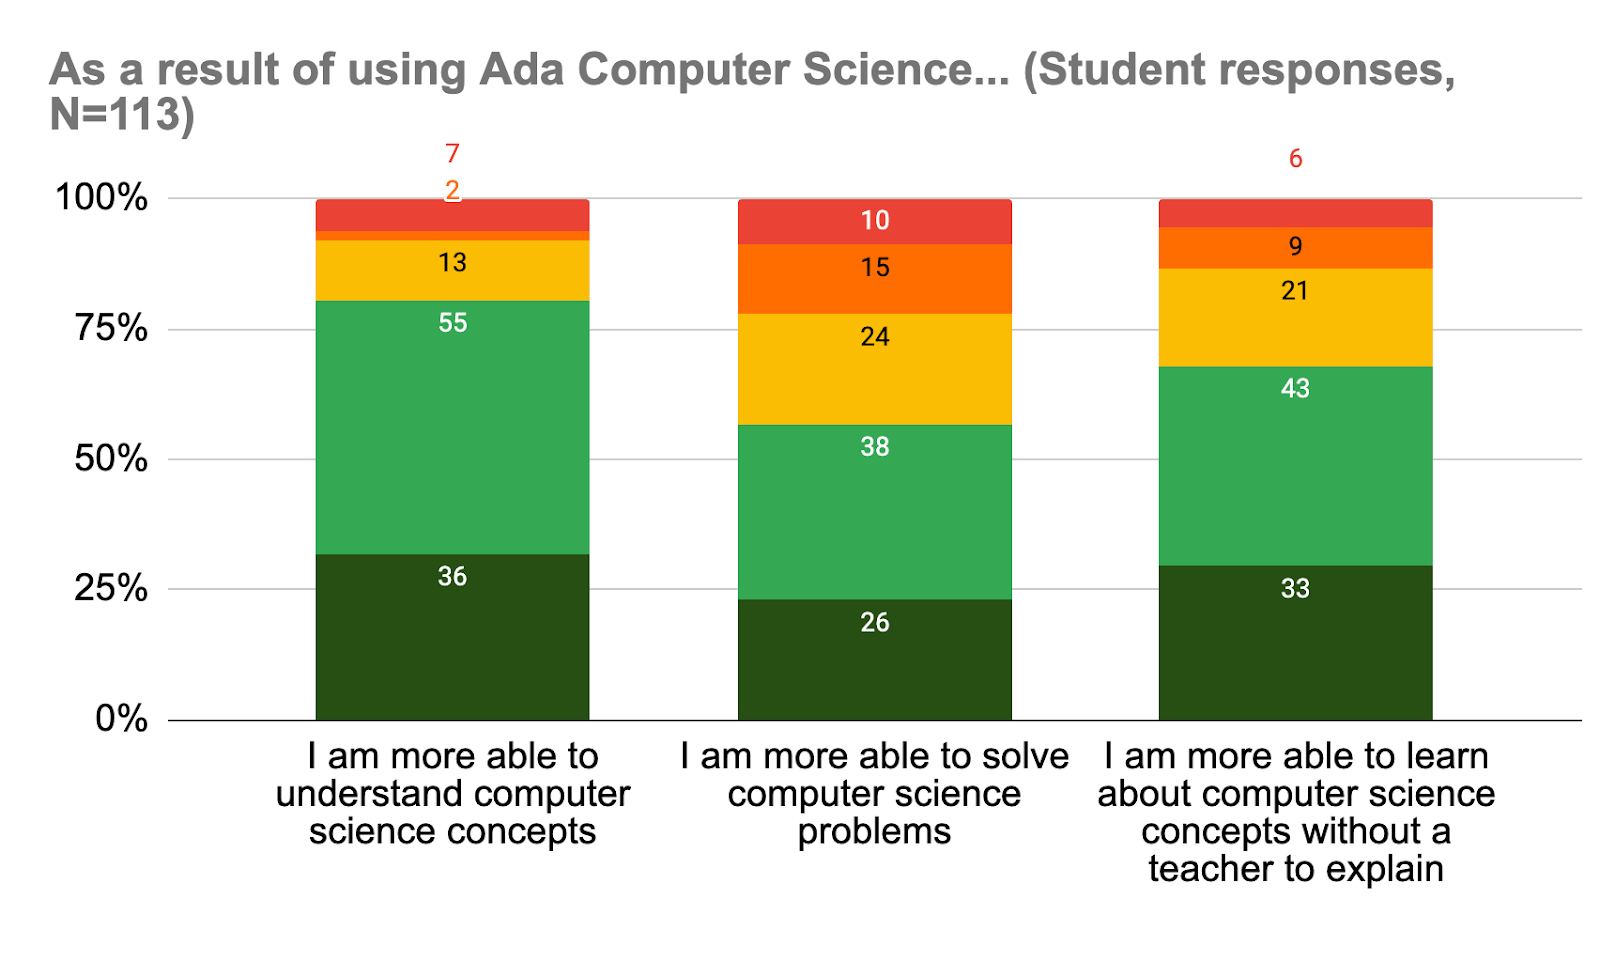
Additionally, 81% of students agreed that as a result of using Ada, they had become better at understanding computer science concepts. Other benefits were reported too, with most students agreeing that they had become better problem-solvers, for example.
“I love Ada! It is an extremely helpful resource… The content featured is very comprehensive and detailed, and the visual guides… are particularly helpful to aid my understanding.” — Student
Future developments
Since receiving this feedback, we have already released updated site navigation and new question finder designs. In 2025, we are planning improvements to the markbook (for example, giving teachers an overview of the assignments they’ve set) and to how assignments can be created.
If you’d like to read more about the findings, there’s a full report for you to download. Thank you to everyone who took the time to take part — we really value your feedback!
The post Ada Computer Science: What have we learnt so far appeared first on Raspberry Pi Foundation.
Отново на кръстопът: Българската външна политика между Вашингтон и Москва
Post Syndicated from Искрен Иванов original https://www.toest.bg/otnovo-na-krustoput-bulgarskata-vunshna-politika-mezhdu-vashington-i-moskva/

Исторически факт е, че геостратегическото разположение на България неведнъж е имало решаващо значение за външната политика на нашата страна както в положителен, така и в негативен план. Кой знае защо, поколения български интелектуалци посочваха този факт с нескрита гордост, като че ли българската външна политика следва да бъде продукт от нашето географско аз, пречупено през балканския постсоциалистически манталитет на голяма част от политиците ни. Но това, разбира се, е само едната страна на монетата.
Съществува и едно сенчесто, трудно доловимо измерение на външнополитическия процес у нас, което обикновено се пренебрегва с аргумента, че не е от решаващо значение, особено след края на Студената война и падането на социализма в България. Точно там е работата обаче, че разпадът на социалистическата система и началото на Прехода ознаменуваха един добре прикрит геополитически консенсус за бъдещето на нашата страна, който беше не толкова плод на българския политически живот, колкото на договарянето на нови сфери на влияние, които прекроиха границите на бившия социалистически лагер в полза на САЩ.
Мнозина български политици са склонни да гледат с носталгия към тези години, защото тогава изборът на България беше относително прост. В сегашните геополитически условия обаче задачата на политическия елит се усложнява от два факта. Първият – че консенсусът между Вашингтон и Москва за постсоциалистическия блок вече не съществува, и вторият – че на България отново се пада незавидната съдба да изпие горчивата чаша на нов геополитически избор, който ще предопредели бъдещето и на идните поколения. В този материал ще се опитаме да анализираме точно тази реалност, за която се говори плахо и нерешително както от политиците, така и от много анализатори.
Постсоциалистическата реалност в българската външна политика
Теорията за постсоциалистическата реалност във външната политика на балканските страни е разработена от група американски историци начело с професорката от Тексаския университет Мери Нюбъргър. Непосредствено след разпадането на СССР учените лансират тезата, че демокрациите в тези държави и в бившия социалистически блок като цяло ще се отличават коренно от демокрацията в САЩ и Западна Европа. В този контекст можем да разграничим няколко основни периода в българската външна политика след падането на социализма у нас.
Първият период започва след срещата между американския президент Джордж Буш-старши и последния съветски лидер Михаил Горбачов през декември 1989 г. в Малта. На тази среща се обсъжда бъдещето на социалистическия блок след началото на дисидентските движения и „нежните революции“ и в крайна сметка се постигат три основни договорки. Първата е готовността на Горбачов да приеме обединението на все още разделената Германия и пълноценното ѝ интегриране в НАТО, а с втората Москва дава възможност на страните от Централна Европа да изберат самостоятелно геополитическия път на своето развитие – предрешен избор, който по-късно ще постави тези държави в американската зона на влияние.
За България и Румъния е постигнат консенсус влиянието на Вашингтон и Москва да бъде поделено 50:50 поради стратегическото разположение на двете страни. И ако анализираме внимателно анатомията на Прехода у нас, ще видим, че неговите архитекти работиха точно в тази посока – военно-политически и икономически България се обвърза с Европейския съюз и САЩ и стана част от евроатлантическото семейство, но енергийно и културно тя остана в руската сфера на влияние. В този смисъл присъединяването на страната ни към ЕС и НАТО не разчупи, а напротив – циментира този консенсус и легитимира архитектите на Прехода, както и тяхната стратегия да позиционират България като междинна зона, където интересите на Вашингтон и Москва се пресичат.
Вторият период в българската външна политика започна веднага след като България стана част от европейското семейство и колективната система за сигурност на НАТО. Покрай цялата еуфория, някак си незабелязано и паралелно с това, беше реабилитиран образът на Русия като партньор на нашата страна. На макрониво това извърши не кой да е, а самата Европа, тъй като европейските елити години наред нямаха проблем София и Москва да развиват сътрудничеството си в сферата на енергетиката, културата и дори икономиката.
Особено силен застъпник на този консенсус беше Германия, която неусетно се превърна в един от най-големите приятели на Русия в Европа – така руското влияние в Източна Европа беше гарантирано, а канцлерът Герхард Шрьодер се оказа сред най-големите привърженици на (тогава) новоизбрания руски президент Владимир Путин. Или казано с други думи, ако през 90-те години в България хората се мусеха, когато чуеха някой да говори на руски, това започна да става все по-привлекателно и някак си модерно, след като страната ни беше приета в европейското семейство.
В лицето на България обаче Вашингтон виждаше съюзник и затова се стараеше да балансира между отношенията си с Москва и военното си присъствие у нас. Така присъединяването на нашата страна към НАТО беше не толкова уникална заслуга на група български политици, а продукт от консенсуса между САЩ и Русия, който новите дисиденти – много от тях с добре известно минало – си приписаха като изключителна заслуга и така легитимираха политическия си мандат.
В тези условия политическият елит у нас управляваше необезпокояван, тъй като САЩ пазеха небето ни, Европа даваше пари по еврофондовете, а Русия щедро градеше културни връзки за приятелство с България, скрепени с огромните газови тръби на „Южен поток“. Към тази конфигурация беше добавен и Китай с неговото намерение да инвестира в мащабни инфраструктурни проекти у нас, а политическият елит – малка част от който вероятно е чел за Конфуций – изработи златния аргумент, че България е една от първите страни в света, признали Китайската народна република.
Идилията обаче беше прекалено хубава, за да продължава, и така се озовахме на прага на третия етап от геополитическото съзряване на постсоциалистическа България, когато консенсусът между Вашингтон и Москва рухна, след като Русия нахлу в Украйна. Доказателство за началото на този етап е, че малко преди Кремъл да даде фаталната за Европа заповед, Путин призова НАТО да се изтегли от България и Румъния, намеквайки, че САЩ трябва да спазват червените линии, които са очертани някога от Малтийския консенсус. На това президентът Байдън отговори, че Русия няма право на сфери на влияние и че САЩ имат свещени задължения към тези нации, които ще спазят по силата на Вашингтонския договор.
А по това време в България и Румъния вече бяха започнали значими политически промени, нови „нежни революции“, които целяха и окончателното откъсване на двете страни от руската сфера на влияние. Политическият елит, който говореше за баланс и консенсус във външната политика, отдавна не беше на мода в Румъния. В България обаче се оказа точно обратното – голяма част от избирателите и политиците гледаха с нескрита носталгия към Малтийския консенсус, не желаеха да се разделят с него или поне бяха против радикални промени в българската външна политика, които да се усетят както на икономическо, така и на културно ниво.
Уви, Европа не можеше да помогне, тъй като Ангела Меркел отдавна вече не беше на власт, а Макрон виждаше, че войната в Украйна заплашва пряко границите на Стария континент. В тези условия САЩ се позиционираха като единствения надежден съюзник на България, но администрацията на Байдън нямаше намерение да прави компромиси нито с корупцията в страната, нито с липсата на културен плурализъм.
Защо България не пожела разчупване на консенсуса?
Първата и основна причина, поради която България не пожела да разчупи Малтийския консенсус във външната си политика, е историческа и може да бъде проследена в годините преди 10 ноември 1989. Моделът, по който е построен българският социализъм, е уникален за Източния блок, тъй като в това семейство няма по-лоялен съюзник на СССР от Народна република България. Често, но погрешно се приема, че причините за това се коренят в Освобождението.
Причините за силната привързаност към социализма в лоялни съветски сателити като България почиват върху два стълба. Единият е спецификата на българския социализъм, който посредством Живковата конституция гарантира пълна лоялност от страна на гражданите към член първи, легитимиращ господстващата роля на БКП. Другата страна на монетата е, че подобно на демокрацията, социализмът у нас също е строен като социализъм с български характеристики. Липсата на свободна инициатива, предвидимостта в битовите отношения, невъзможността за истинска конкуренция и свобода на пазара спомагат за формирането на нагласи, които виждат в амбициозния и преуспял западен човек, свободен от всякакви морални ограничения, враг на социалистическия строй и на традицията.
В същото време образователната система изработва ефективни механизми за представянето на САЩ като капиталистически генератор на конфликти – теория, която, уви, днес се отстоява от много леви интелектуалци в Америка и у нас. Това фалшиво усещане за свобода под шапката на Москва рухва по време на Възродителния процес, когато става ясно, че времето на „спокойните хора“ вече е отминало, а след идването на Горбачов на власт различията между съветското и българското ръководство естествено доведоха до падането на социализма у нас. В тези условия политиците гледаха на Америка като на „новия голям брат“, който ще измести СССР като гарант за сигурността на страната ни. И затова по време на Прехода България заимства именно американския икономически модел, а не европейския, за да възстанови икономиката си след кризата от 1996–1997 г.
И все пак българинът успя да съхрани носталгията по социализма както никой друг народ в Европа. Това е и втората причина, поради която разчупването на Малтийския консенсус изглежда почти невъзможно. Най-парадоксалното е, че тази носталгия се дължи не на някакви обективни политически причини, а просто на факта, че голяма част от носталгиците хранят такива чувства поради възрастта си. Проблемът няма как да бъде преодолян, тъй като има психологически характер и е обективно следствие от формата на социализъм, която доминираше в страната в продължение на 45 години.
За съжаление, голяма част от младото поколение също не е способно да компенсира този дефицит по множество причини. От една страна, е проблемът с демографията и емиграцията, а от друга страна – липсата на толерантна и плуралистична среда, която да генерира и насърчи професионалното развитие на младото поколение. Дали посочените проблеми могат да бъдат преодолени на този етап, е спорно поради политическата нестабилност в страна и липсата на желание за изграждане на дългосрочни стратегии.
Третата група причини засяга устойчивото руско влияние в страната и перспективата то да бъде заменено от сходни по идеология формули. Силната лоялност на България към СССР от времето на Студената война, която се запази устойчива след формирането на българския постсоциалистически елит, и дългосрочното нежелание на Европа да погледне сериозно на проблемите, с които се сблъсква обществото ни години наред, доведоха до политическа нестабилност, която изглежда непреодолима поради невъзможността за откриване на единна формула за българския национален интерес.
Докато такава липсва, патриотичните фракции ще продължат да гледат на понятието български национален интерес като на възможност да увеличат подкрепата си и да държат България колкото е възможно по-близо до своите идеи, а прозападните и ястребските крила да задълбочат механичната си реторика за цивилизационния избор на страната да бъде част от ЕС и НАТО.
Това противопоставяне в обществото е основният генератор на конфликти, който не позволява разчупването на Малтийския консенсус и изработването на последователна стратегия, която да позиционира България трайно на геополитическата карта. Конспиративна теория е да смятаме, че тази поляризация крие някакви тайни, скрити измерения и че някой нарочно разделя българите, за да не могат да постигнат консенсус за интересите си.
Такива теории обикновено кореспондират с митовете, че американските президенти си лягат и стават с мисълта дали в България трябва да има редовно правителство, или не. Всъщност не САЩ, а българските избиратели решават това – и така ще отговори всеки американски дипломат. Лошата новина е, че в българското общество няма воля за разчупването на Малтийския консенсус и заради това той трябва да бъде заменен от някаква приемлива геополитическа формула, която да възстанови политическата стабилност у нас.
(Следва продължение.)
Зад кулисите на изслушванията за еврокомисари
Post Syndicated from Анахит Хачикян original https://www.toest.bg/zad-kulisite-na-izslushvaniyata-za-evrokomisari/

Докато в България партиите са вгледани самовлюбено в резултатите от изминалите избори и в поредните напъни за съставяне на правителство, българските евродепутати в Брюксел вече са заели местата си в парламентарните комисии, в които са избрани да членуват, и се опитват да влязат в работен ритъм, всеки според възможностите и интересите си.
Звезден миг за гражданската легитимност
През изминалите две седмици българските евродепутати участваха в изслушванията на кандидат-комисарите в Брюксел. Това несъмнено е един от звездните моменти за Европейския парламент, който се повтаря на всеки пет години непосредствено след европейските избори. Новоизбраните депутати във всяка парламентарна комисия препитват като на изпит кандидат-комисарите, предложени от правителствата на държавите членки. Ако дадените отговори не се харесат на депутатите, кандидатурата може да бъде отхвърлена и трябва съответната държава, изпаднала в немилост, да предложи нов кандидат, който да бъде подложен на същото изпитание.
Моментът е звезден, защото Европейският парламент е единствената институция, избрана пряко от гражданите на Европа и точно изслушванията на кандидат-комисарите са един от начините тази гражданска легитимност да бъде упражнена. Представени от депутатите, европейските граждани са всъщност тези, които косвено се произнасят по кандидатурите на бъдещите комисари, и то не по национален признак, а в зависимост от тяхната компетентност и познания в сферата, в която са номинирани.
Така Парламентът има решаваща роля за състава на следващата Комисия, от която пък ще зависи какво законодателство ще бъде предложено на европейско ниво, какъв бюджет ще бъде отпуснат по различните програми, какви средства ще бъдат одобрени по различни проекти и много други въпроси с конкретни последици на всички нива. Макар и да не взема крайните решения, Европейската комисия е институцията, която предвожда законодателния процес, предлагайки законите и дефинирайки първоначалните им рамки на действие и обхват. Затова е от ключово значение кой управлява всяко от 26-те портфолиа.
Изслушването
Като всеки звезден миг, и този е добре режисиран предварително. В рамките на десет дни са организирани 26 изслушвания, като първото за деня започва в 9:00 ч. сутринта, а последното приключва в 21:30. Преди да се изправят на изпитната скамейка, кандидат-комисарите имат седем седмици да се подготвят. Получават инструкции от сътрудниците на напускащите комисари, срещат се с представители на различни политически групи, с координаторите и председателите на парламентарните комисии, с представители на неправителствени организации и лобита; отговарят на списък от писмени въпроси на евродепутатите и подготвят 15-минутна реч, в която да представят приоритети си за следващите пет години.
По време на самото изслушване обаче те трябва да отговарят импровизирано и именно по този начин се разбира доколко са запознати с ресора, който ще ръководят, и дали имат ясна визия за това, с което ще се занимават. На изслушванията, освен евродепутатите, присъстват много журналисти, фотографи, политически съветници, пиари и сътрудници. Зад катедрата седят председателите на парламентарните комисии от ресора на кандидат-комисаря, а пред тях на една малка маса е самият кандидат, готов за тричасов кръстосан разпит. Напрежението в залата е осезаемо.
Освен че крайният резултат зависи от индивидуалното представяне на всеки кандидат, политическите групи в Парламента също обсъждат цялостния състав на Комисията и се опитват, от една страна, да подкрепят кандидатите от своето политическо семейство, а от друга страна, да не атакуват прекалено опонентите си, за да не им се върне тъпкано.
Санитарен кордон и в Европарламента
В проектния състав на следващата Комисия има 16 кандидат-комисари на десни правителства, четирима кандидати на леви правителства, петима кандидати либерали и един кандидат-комисар от десницата на Мелони в Италия. Това съотношение между политическите сили в бъдещата Европейска комисия не отразява състава на новия Парламент, където крайнодясната политическа група „Патриоти за Европа“ е третата по големина, но няма нито един кандидат за комисар, нито пък председатели или заместник-председатели на парламентарни комисии.
Причината за това е прилагането на санитарен кордон от левицата, либералите и зелените, за да предотвратят заемането на ключови позиции от крайнодесните. Самата кандидатура на Урсула фон дер Лайен за втори мандат начело на Комисията беше одобрена в края на лятото от левицата, либералите и зелените, при условие че няма да има представители на крайната десница сред новите комисари. Въпреки това няколко месеца по-късно крайнодесният италианец Рафаеле Фито, съпредседател на Групата на европейските консерватори и реформисти в предишния мандат на Европарламента, не само беше издигнат за италиански кандидат-комисар в следващата Комисия, а и за неин изпълнителен заместник-председател.
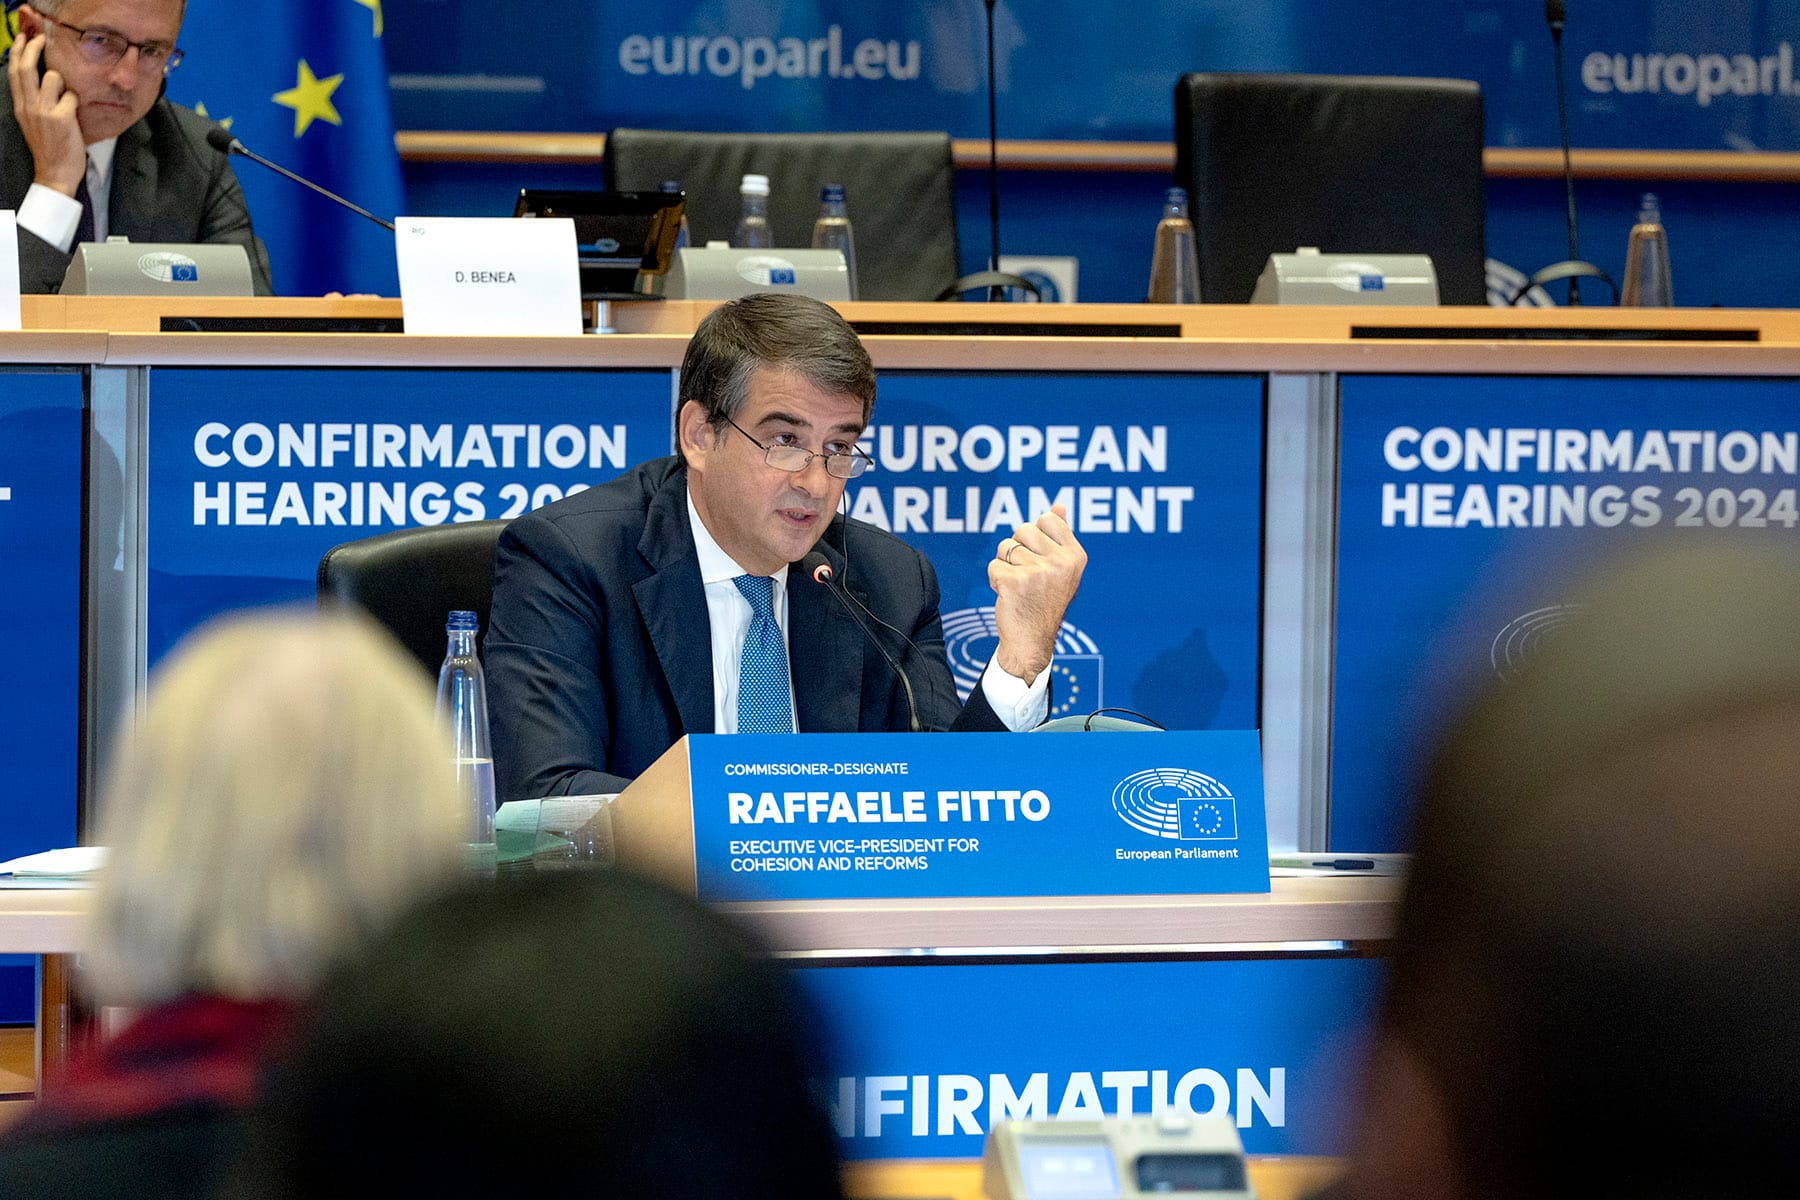
Санитарният кордон е неписано правило и подлежи на гъвкави интерпретации, особено в настоящия Европарламент, където, ако традиционната десница на Европейската народна партия се обедини с другите крайнодесни партии, ще държи под контрола си половината пленарна зала. Подобно обединение на десницата в бъдеще, ако се окаже трайно и стабилно, коренно ще промени съотношението на силите между политическите групи в Парламента. Ако в последните десет години трите най-големи групи – на десните, левите и либералите – съставяха съвместно законодателни предложения след дълги преговори и постигане на компромис, сега Парламентът започва да се връща към модел, по-близък до националните парламенти – с класически идеологически противопоставяния между партиите и ясно очертани мнозинство и опозиция. При такава конфигурация рисковете от блокажи и задънени улици значително се увеличават.
Именно това се случи в Европейския парламент в края на изслушванията за еврокомисари, след като 19 от 26-имата кандидати вече бяха препитани и одобрени. Под натиска на десницата изслушванията на последните шестима кандидат-комисари и бъдещи изпълнителни заместник-председатели на Комисията, сред които Тереса Рибера (испанска левица) и Рафаеле Фито (италианска крайна десница), бяха оставени за обсъждане и групово одобрение в последния ден. Така десницата се надяваше кандидатурата на крайнодесния Фито да мине между капките и да бъде одобрена в цялостния пакет на висши назначения.
Левицата обаче продължи яростно да се съпротивлява, настоявайки, че тази кандидатура противоречи на първоначалното споразумение и нарушава санитарния кордон. Тогава десницата мина в контранастъпление и се възползва от неотдавнашните поройни дъждове в Испания, за да атакува испанската кандидатка за комисар и настояща министърка на екологичния преход в Испания – Рибера, като я обвини за бедственото положение в засегнатите региони.
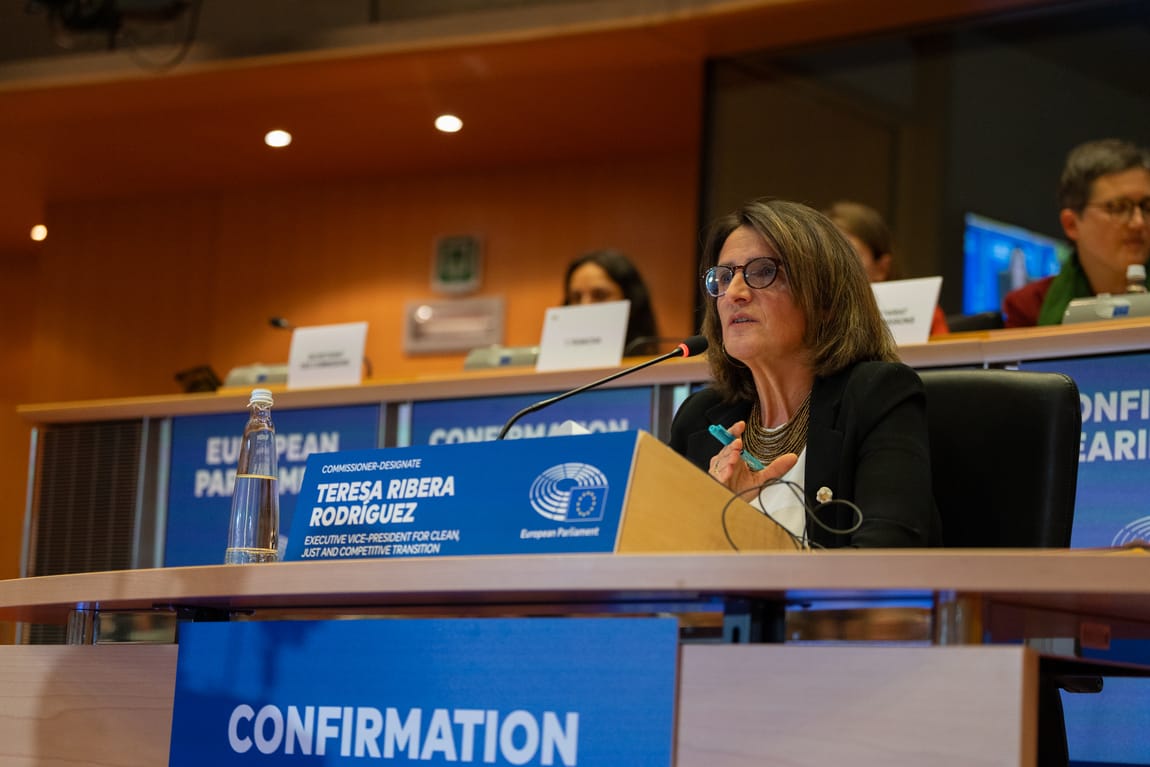
Така в последния ден от изслушванията страстите се нажежиха и вместо да дискутират европейски политики, евродепутатите и целият бъдещ състав на Комисията се оказаха заложници на вътрешнополитически конфликти, а приличното представяне на индивидуалните кандидати и предварителните споразумения между групите останаха на заден план. Но освен че говорим за борба на власт и влияние между европейските столици, основното предизвикателство тук е идеологическото позициониране на европейските институции и дали постепенно ще минават все по-вдясно и ще водят все по-консервативни политики, или ще запазят досегашното си относително равновесие в смесица от десни, леви и либерални идеи.
Ако политическите групи не постигнат бързо съгласие и предложеният състав на Комисията не бъде гласуван на пленарната сесия в края на ноември, встъпването в длъжност на новите екипи ще остане за следващата година, което не е най-добрият сценарий в един бързо променящ се и непредвидим свят след завръщането на Тръмп в Белия дом.
Къде сме ние?
Българската кандидатка за комисар Екатерина Захариева (ГЕРБ) беше изслушана в Комисията по промишленост, изследвания и енергетика. Това е същият ресор, който България имаше и в предишната Комисия, но този път без културата и младежта, които сега са прибавени към спорта в отделно портфолио, дадено на Малта.
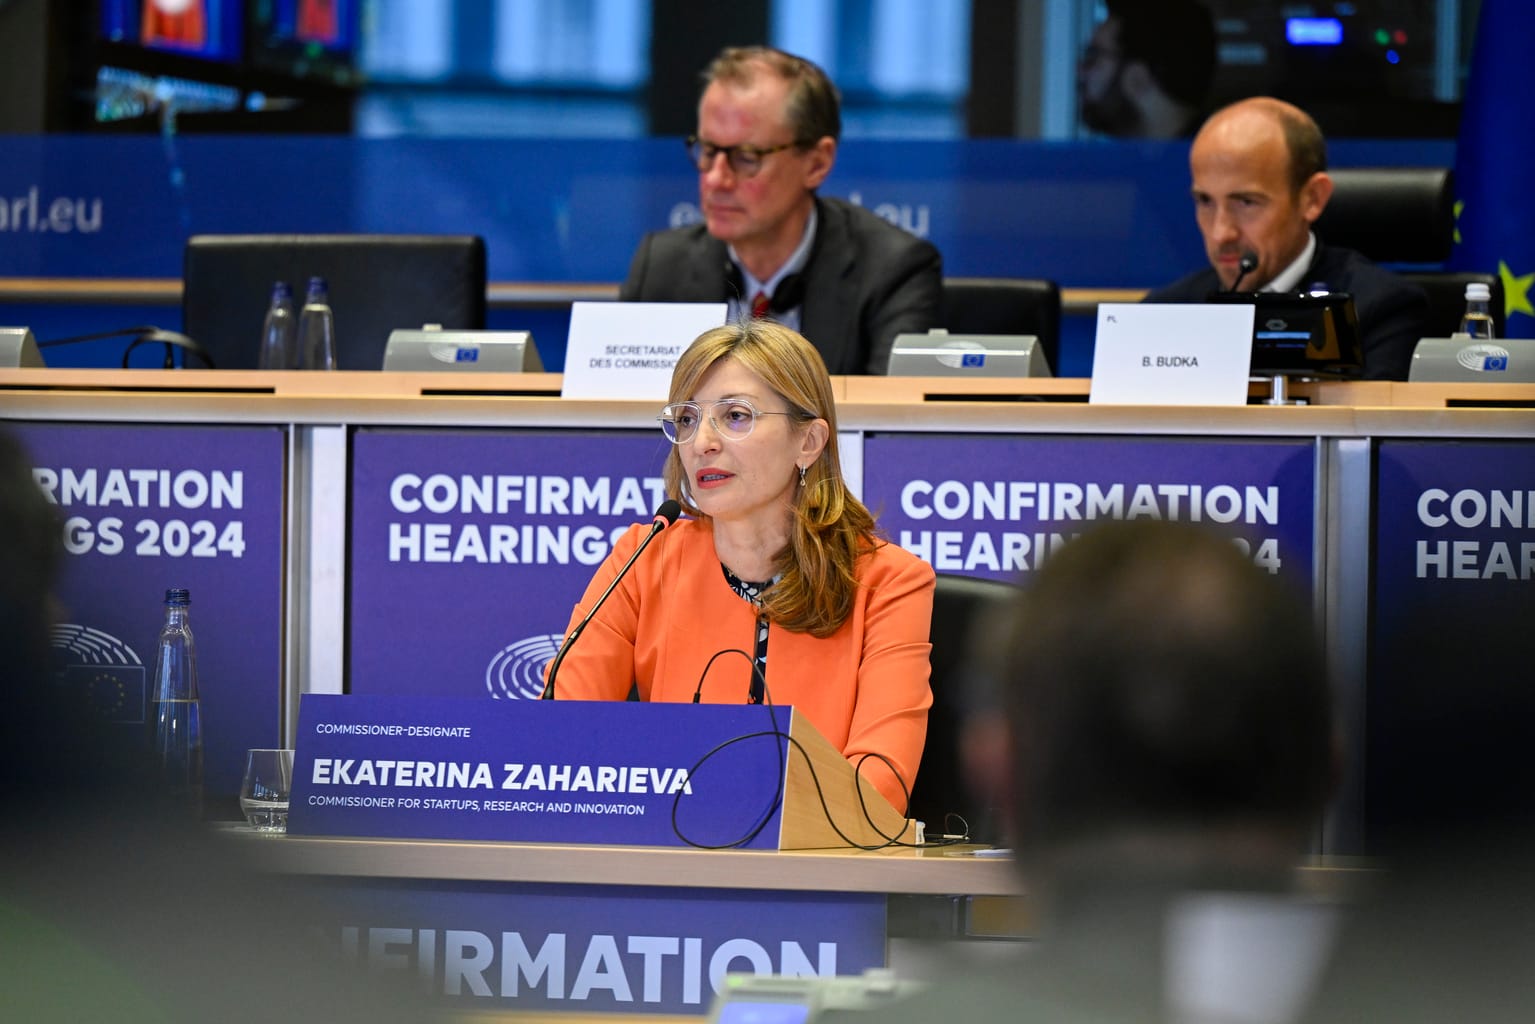
Захариева постави акцент върху увеличаването на инвестициите в сферата на научните изследвания и иновациите, както и върху необходимостта частният сектор също да бъде привлечен да инвестира. Други приоритети в работата ѝ ще бъдат насърчаването на участието на жени изследователки във всички научни области, намаляването на бюрокрацията, а също и инвестиции за научни изследвания в отбраната. Захариева цитира много статистики от европейски доклади и изследвания, с което запълни липсващата ѝ лична професионална експертност по темите. Политическият ѝ опит от България пък ѝ помогна да се измъкне ловко от деликатни въпроси, като продължаващото финансиране на израелски университети въпреки случващото се в Газа или рисковете от инструментализиране на средства, отделени за граждански изследвания, и пренасочването им към изследвания за отбрана.
Българската кандидатка се обяви в подкрепа на всички академични институции, независимо от тяхната националност, за да бъде избегната дискриминация. По отношение на военните изследвания тя даде за пример американската Агенция за перспективни изследователски проекти за отбраната (DARPA), подчертавайки, че получените резултати често имат едновременно и военно, и гражданско приложение, така че ползите са повсеместни.
Наред с много други членове на Европейския парламент, българските евродепутати Цветелина Пенкова (БСП), Ева Майдел (ГЕРБ), Петър Волгин („Възраждане“) и Христо Петров („Продължаваме промяната“) също отправиха своите индивидуални въпроси към Екатерина Захариева съвсем в рамките на добрия тон и далеч от обичайната за България агресивна политическа конфронтация.
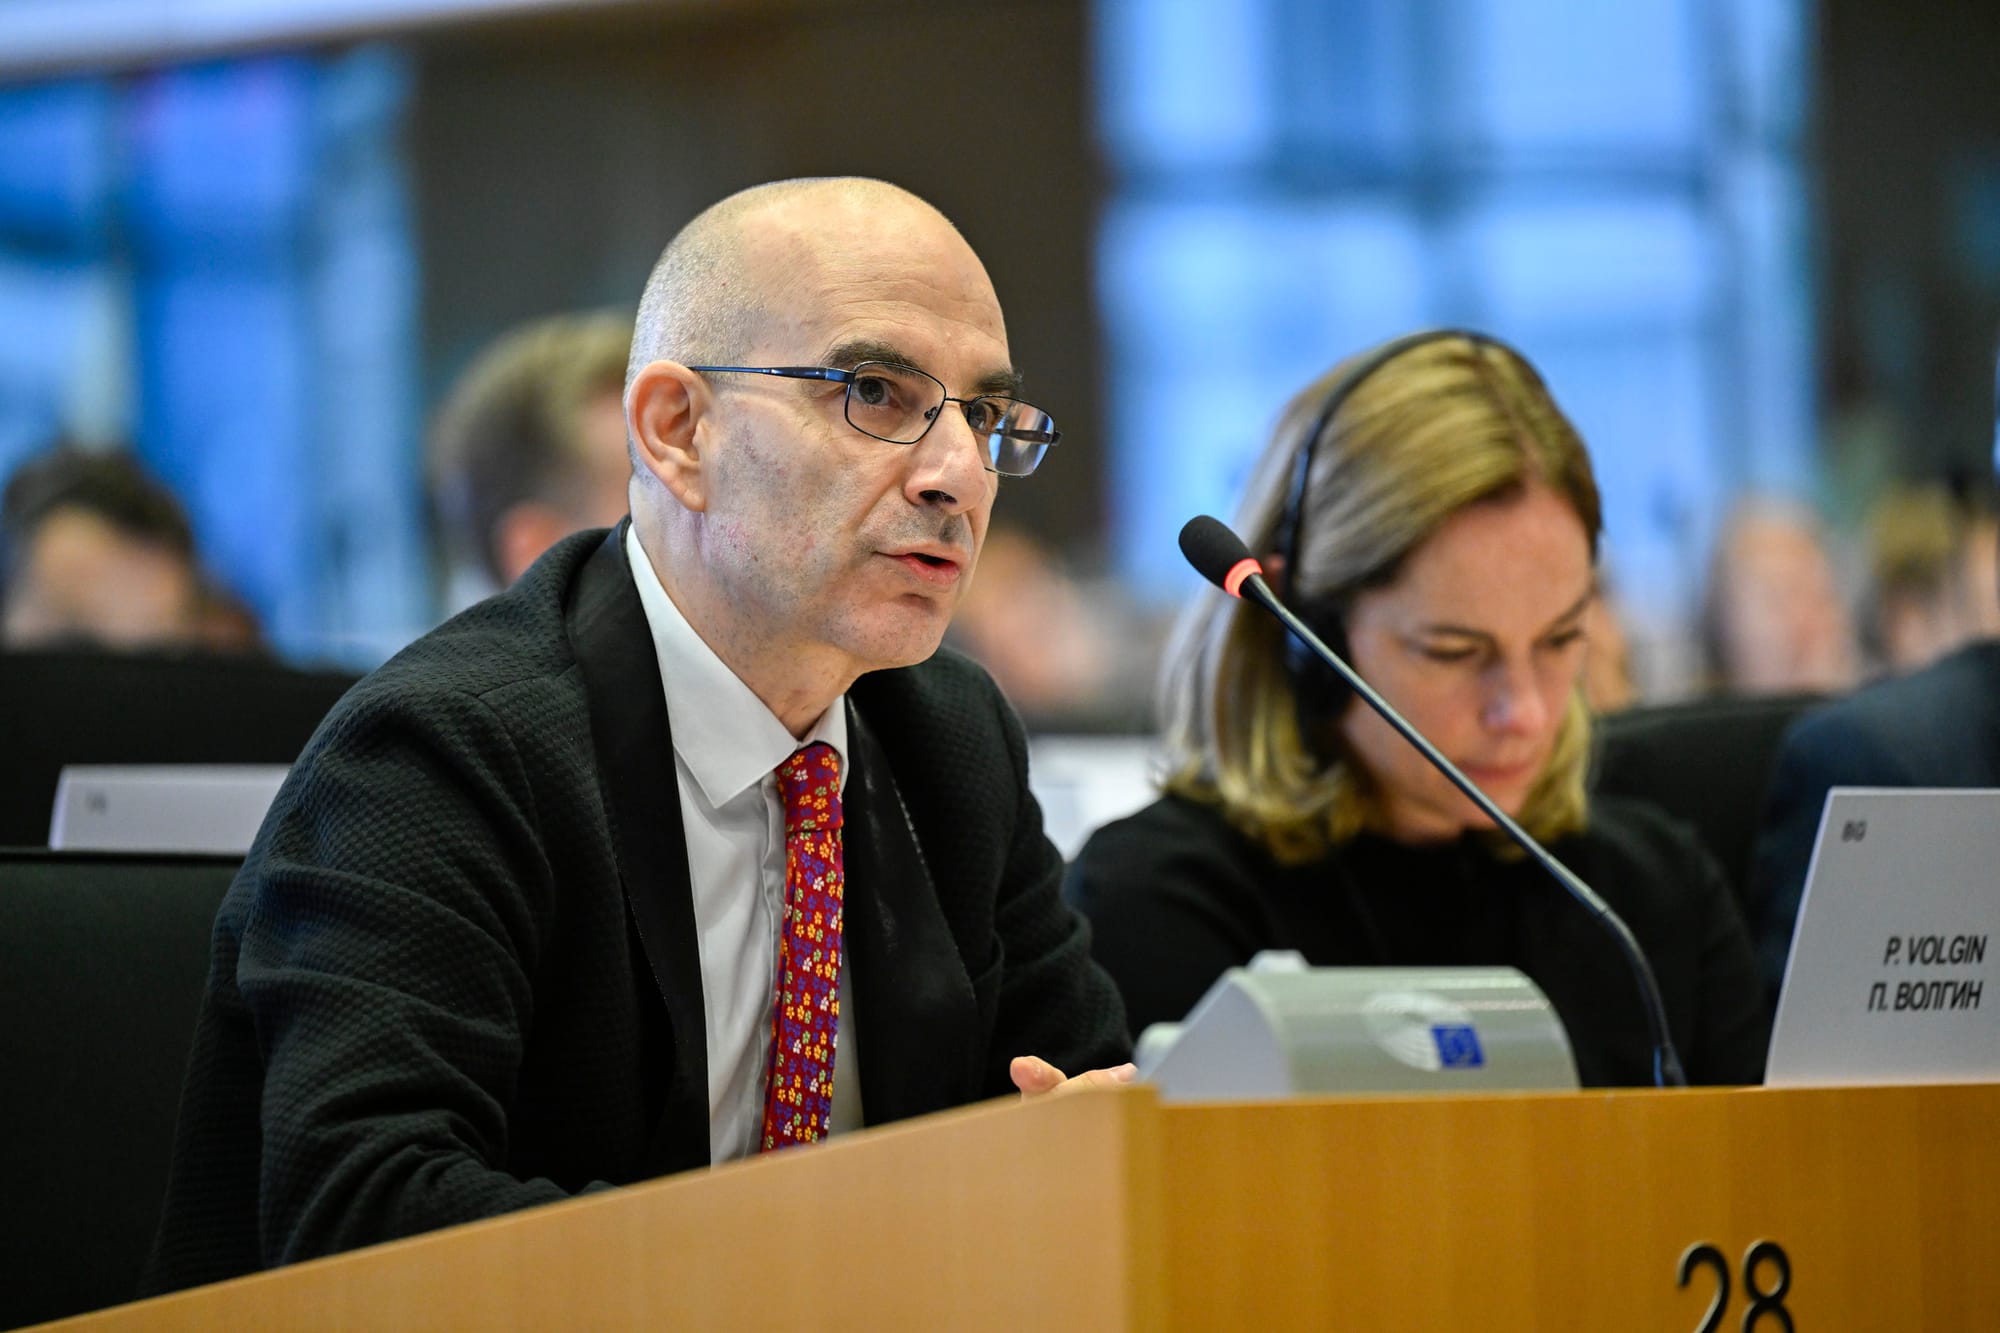
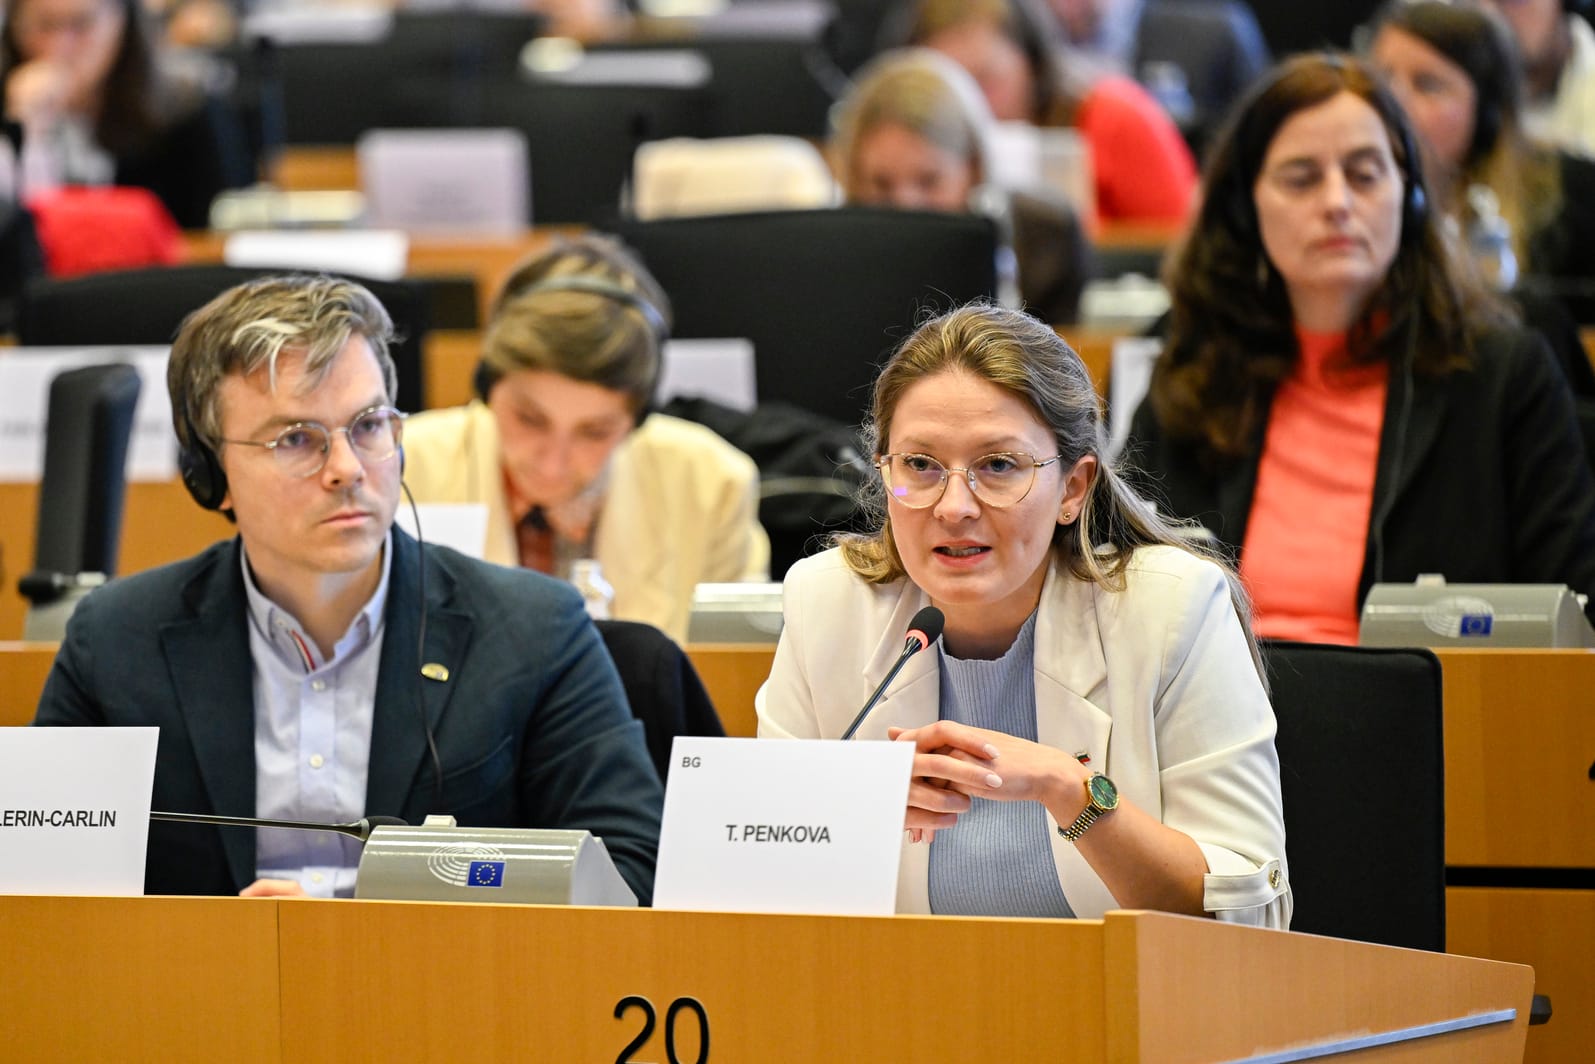
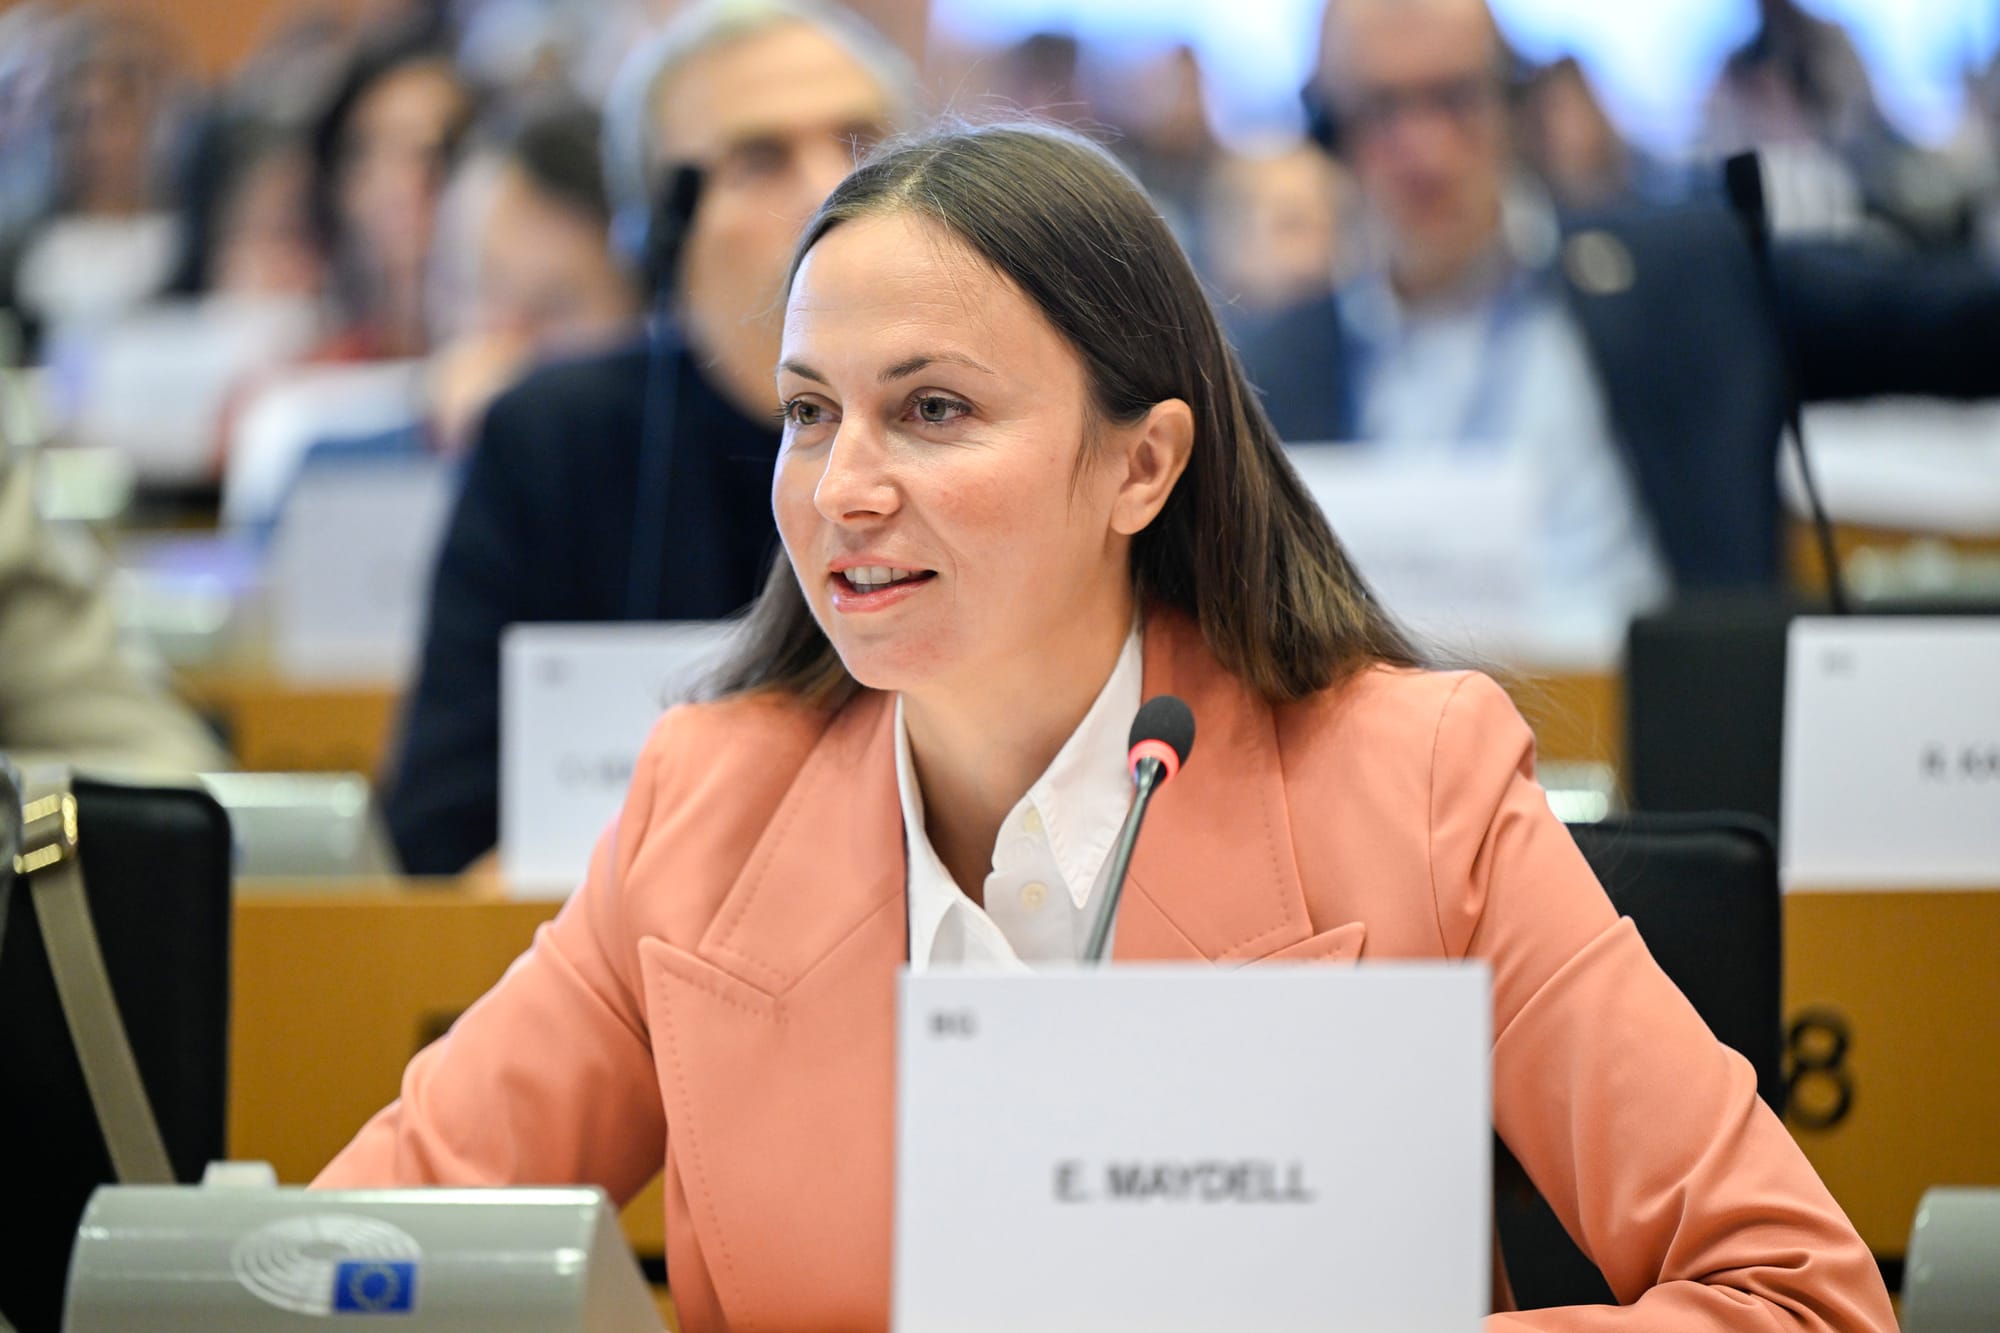
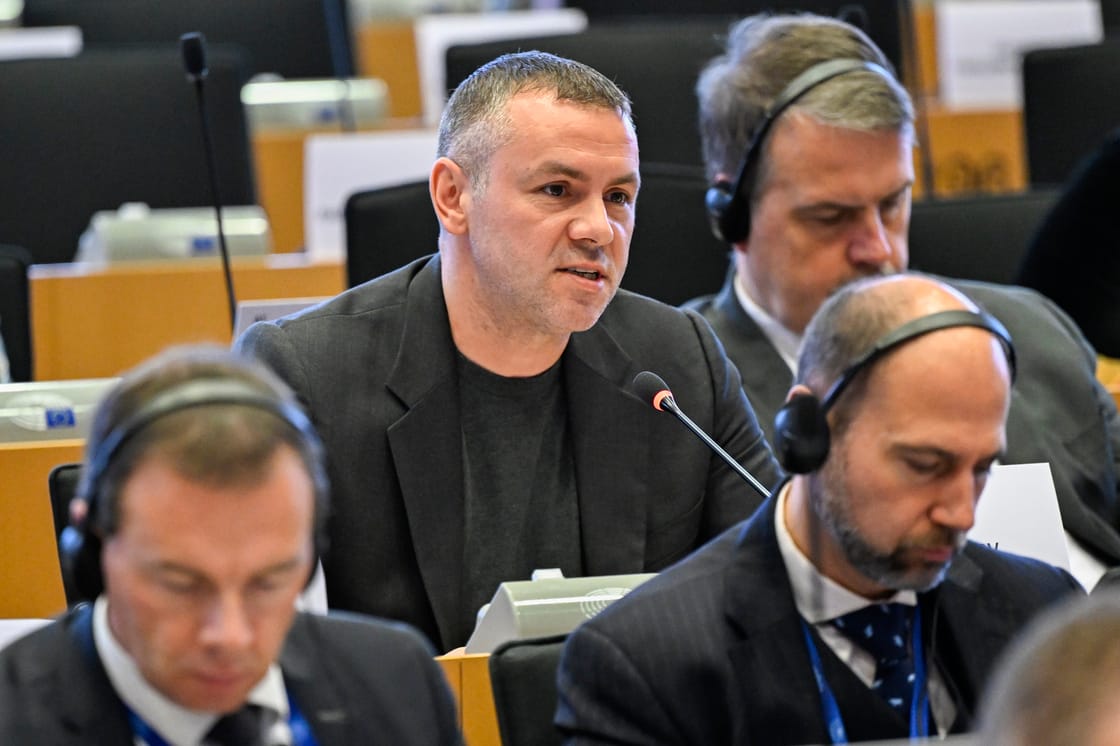
Българските евродепутати, задаващи въпроси на Екатерина Захариева по време на нейното изслушване за еврокомисар © European Union 2024 – Source: EP
След изслушването шестима от присъстващите седем координатори на изпитващата парламентарна комисия одобриха кандидатурата на Екатерина Захариева. Само крайната левица гласува против, а депутатите от групата на „Европа на суверенните нации“, част от която е и българската „Възраждане“, не присъстваха на гласуването.
Какво означава това за България?
От влизането на България в Европейския съюз досега всички български комисари са били жени с политически опит на национално, европейско или международно ниво. Преди да станат еврокомисари, Меглена Кунева е била министър по европейските въпроси, Кристалина Георгиева – вицепрезидент на Световната банка, Мария Габриел – евродепутат, а Илиана Иванова – член на Европейската сметна палата. Екатерина Захариева е била зам.-министър на регионалното развитие и благоустройството, министър на правосъдието и министър на външните работи.
Женските кандидатури за български еврокомисар се гледат с добро око в една Европа, която все още руши стереотипи и се бори за равенство между половете. Погледнато в по-мащабен план, цялостният образ на българския комисар, от нивото на владеене на чужди езици и начина на обличане и поведение до знанията в ресора и политическата опитност, оказват влияние за изграждането на образа на България на европейско ниво. Българите, работещи в европейските институции от дълги години, още си спомнят скандалното изслушване на една друга българска кандидатка за еврокомисар – Румяна Желева. През 2009 г. тя предизвика масово възмущение с лъжливите си декларации, лошия си английски и пълната си неподготвеност по зададените въпроси и както се очакваше, беше отхвърлена от евродепутатите.
Българските политици в Брюксел имат ключова роля за изграждането на образа на страната ни на международната сцена, а това влияе не само в политически план, а и по отношение на чуждестранните инвестиции, международното сътрудничество в различни сфери и дали въобще ни вземат на сериозно. Достойното участие на България в дебати по теми като Зелената сделка, миграционната политика или социалните неравенства ни приобщава към търсенето на решения на глобални проблеми и ни включва в европейските политически процеси. Помага ни да разбираме по-добре предизвикателствата в света, в който живеем.
От друга страна, международната среда, в която са българските представители в Брюксел, и работата им с колеги от цяла Европа биха могли постепенно да окажат положително влияние върху начина на правене на политика в България, да внесат професионални практики, като конструктивния диалог, коалициите, основани на идеи и ценности, балансираните преговори за постигане на печеливш за всички компромис. Все ценности, които са съставна част от изграждането на демократично и гражданско общество и които биха довели до нормализация на политическите процеси, ако има кой да ги внесе на родна земя.
Изразеното мнение е лично и не представлява позицията на Европейския парламент.
This is the New NVIDIA GB200 NVL4
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/this-is-the-new-nvidia-gb200-nvl4-arm-grace-blackwell/
We found the new NVIDIA GB200 NVL4 on the SC24 show floor the same day that it was announced showing off a new node design
The post This is the New NVIDIA GB200 NVL4 appeared first on ServeTheHome.
To shoot down Soviet Bombers.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=l62RTCy0yRU
YACE is joining Prometheus Community
Post Syndicated from Thomas Peitz (@thomaspeitz) original https://prometheus.io/blog/2024/11/19/yace-joining-prometheus-community/
AlmaLinux 9.5 released
Post Syndicated from corbet original https://lwn.net/Articles/998637/
Version 9.5 of the AlmaLinux enterprise-oriented distribution has been
released.
AlmaLinux 9.5 aims to improve performance, development tooling, and
security. Updated module streams offer better support for web
applications. New versions of compilers provide access to the
latest features and optimizations that improve performance and
enable better code generation. The release also introduces
improvements to system performance monitoring, visualization, and
system performance data collecting.
Comic for 2024.11.19 – The Spectrum
Post Syndicated from Explosm.net original https://explosm.net/comics/the-spectrum
New Cyanide and Happiness Comic
YACE is joining Prometheus Community
Post Syndicated from Thomas Peitz (@thomaspeitz) original https://prometheus.io/blog/2024/11/19/yace-joining-prometheus-community/
Yet Another Cloudwatch Exporter (YACE) has officially joined the Prometheus community! This move will make it more accessible to users and open new opportunities for contributors to enhance and maintain the project. There’s also a blog post from Cristian Greco’s point of view.
The early days
When I first started YACE, I had no idea it would grow to this scale. At the time, I was working with Invision AG (not to be confused with the design app), a company focused on workforce management software. They fully supported me in open-sourcing the tool, and with the help of my teammate Kai Forsthövel, YACE was brought to life.
Our first commit was back in 2018, with one of our primary goals being to make CloudWatch metrics easy to scale and automatically detect what to measure, all while keeping the user experience simple and intuitive. InVision AG was scaling their infrastructure up and down due to machine learning workloads and we needed something that detects new infrastructure easily. This focus on simplicity has remained a core priority. From that point on, YACE began to find its audience.
Yace Gains Momentum
As YACE expanded, so did the support around it. One pivotal moment was when Cristian Greco from Grafana Labs reached out. I was feeling overwhelmed and hardly keeping up when Cristian stepped in, simply asking where he could help. He quickly became the main releaser and led Grafana Labs’ contributions to YACE, a turning point that made a huge impact on the project. Along with an incredible community of contributors from all over the world, they elevated YACE beyond what I could have achieved alone, shaping it into a truly global tool. YACE is no longer just my project or Invision’s—it belongs to the community.
Gratitude and Future Vision
I am immensely grateful to every developer, tester, and user who has contributed to YACE’s success. This journey has shown me the power of community and open source collaboration. But we’re not done yet.
It’s time to take Yace even further—into the heart of the Prometheus ecosystem. Making Yace as the official Amazon CloudWatch exporter for Prometheus will make it easier and more accessible for everyone. With ongoing support from Grafana Labs and my commitment to refining the user experience, we’ll ensure YACE becomes an intuitive tool that anyone can use effortlessly.
Try out YACE on your own
Try out YACE (Yet Another CloudWatch Exporter) by following our step-by-step Installation Guide.
You can explore various configuration examples here to get started with monitoring specific AWS services.
Our goal is to enable easy auto-discovery across all AWS services, making it simple to monitor any dynamic infrastructure.
Know before you go – AWS re:Invent 2024 cloud resilience
Post Syndicated from Shllomi Ezra original https://aws.amazon.com/blogs/architecture/know-before-you-go-aws-reinvent-2024-cloud-resilience/
With AWS re:Invent 2024 just weeks away, the excitement is building and we’re looking forward to seeing you all soon. If you’re attending re:Invent with the goal of improving your organization’s cloud resilience operations, we will be offering valuable insights, best practices, and fun activities to improve your cloud resilience expertise.
This year, we’re offering more than 100 resilience breakout sessions, workshops, chalk talks, builders’ sessions, and code talks. Find the complete list in the re:Invent 2024 session catalog and filter by “Resilience” in the area of interest field.
In this post, we highlight must-see sessions for those building resilient applications and architectures on AWS. Reserved seating is now open, so act quickly to claim your seat. Be sure to also check out the vertical-specific re:Invent guides.
Our recommendations are divided into three topics to help you choose the sessions most relevant to your business: resilience fundamentals, advanced resilience patterns, and resilience for customers operating in regulated industries.
What is cloud resilience all about?
Cloud resilience refers to the ability for an application to resist or recover from disruptions, including those related to infrastructure, dependent services, misconfigurations, transient network issues, and load spikes. Cloud resilience also plays a critical role in an organization’s broader business resilience strategy, including the ability to meet digital sovereignty requirements. Resilient applications are those built with high availability—the percentage of time the application is available for use—and also those with a disaster recovery or continuity of operations plan in place.
Resilience fundamentals
Join us as we explore the strategies, tools, and mindsets that enable organizations to thrive in the face of uncertainty. These sessions cover conceptual overviews and demos of AWS cloud resilience services.
Breakout sessions
Failing without flailing: Lessons we learned at AWS the hard way (ARC333)
At AWS, we’ve learned that building resilient services requires more than just designing for high availability. In this session, AWS operational leaders are back for more insights on how to mitigate impact when, not if, the unexpected happens. Hear a few short stories collected from 18 years of operational excellence, with practical advice on preparing for and mitigating failure.
Think big, build small: When to scale and when to simplify (ARC331)
Join this session to learn how to navigate the complexities of cloud architecture. Hear insights and guidance developed from working with successful AWS customers, including how to optimize for business value and agility. Discover the AWS approach to architectural tiers, engineering simplicity and reliability, and treating infrastructure as an investment.
Mastering resilience at every layer of the cake (ARC327)
Join this session to learn resilience at various levels, from platform to applications, using AWS services like AWS Resilience Hub, AWS Fault Injection Service, ARC, Amazon Elastic Disaster Recovery, and AWS Backup. You’ll leave with a mental model for resilience across these layers, and ready-to-use reference architectures and guidance. The session includes demos for a fun, lively experience.
Building resilient applications on AWS with Capital One (ARC334)
In this session, discover the patterns and principles of AWS resilience best practices. Then, hear Capital One showcase its next-generation design and deployment patterns that push the boundaries of resilient architectures and support its most critical business processes. Learn about the AWS services it uses, the trade-offs it must consider, and the decision matrix that guides developers to the right pattern for the right use case.
Data protection and resilience with AWS storage (STG301)
Join this session to dive deep on how AWS storage offers organizations defense-in-depth data protection and resilience for application data across recovery point and time objectives, helping mitigate risks with immutable solutions, restore testing, policy-based access controls, encryption, and auditing and reporting.
Workshops
Building, operating, and testing resilient Multi-AZ applications (ARC303)
Join this workshop to get hands-on experience building, operating, and testing a resilient Multi-AZ application.
Building resilient architectures with observability (COP308)
Explore how to use AWS services, including AWS Resilience Hub, Amazon CloudWatch, and AWS Fault Injection Service, to build resilient and reliable cloud-based applications.
Advanced resilience patterns
Building resilient and reliable applications in the cloud is critical for organizations running mission-critical workloads. Unexpected outages, latency spikes, or performance issues can have severe business impact. The sessions and workshops in this track explore advanced techniques and tools to help you proactively identify and address resilience weaknesses in your systems. Learn how to use chaos engineering, multi-Region architectures, and the latest AWS services and best practices to enhance the resilience and operational excellence of your cloud applications.
Breakout sessions
Chaos engineering: A proactive approach to system resilience (ARC326)
This session demonstrates the benefits of chaos engineering in action. Gain insights from BMW Group’s transformative journey, learning key lessons on scaling chaos engineering across the organization, and how BMW Group conducts large-scale chaos experiments in production, uncovering issues and fostering a culture of greater resilience and continuous improvement.
Try again: The tools and techniques behind resilient systems (ARC403)
Grand architectural theories are nice, but what makes systems resilient is in the details. Marc Brooker, VP and distinguished engineer, looks at some of the resiliency tools and techniques AWS uses in its systems. Marc rethinks, retries, breaks open circuit breakers, decodes erasure coding, and tackles the tail. Learn about formal methods and simulation, and how these tools help build faster code, faster.
Multi-Region or single Region? Considerations and architectures (ARC309)
Watch experts walk through and whiteboard architectures that take advantage of AWS services that support multi-Region capabilities, and discuss what a failover scenario would look like in real life. Leave with an understanding of what it takes to run a multi-Region architecture on AWS.
Best practices for creating multi-Region architectures on AWS (ARC323)
In this session, learn the two critical areas you’ll need to consider. First, explore different failover strategies and the trade-offs between them. Then, learn how to make the decision to initiate a cross-Region failover as well as what goes into the process. Lastly, hear from Samsung Account about their multi-Region application and how they think about these two critical areas.
Workshops
Chaos engineering workshop (ARC322)
This workshop introduces AWS Fault Injection Service for running controlled resilience experiments to improve application performance, observability, and resilience. You must bring your laptop to participate.
Gen AI resilience: Chaos engineering with AWS Fault Injection Service (ARC305)
Learn how to construct a useful hypothesis backlog for generative AI applications and how to use AWS Fault Injection Service to run those experiments. You must bring your laptop to participate.
Building operational resilience in workloads using generative AI (SUP401)
Building operational resilience requires proactive identification and mitigation of risks. In this workshop, use AWS managed generative AI services in real-world scenarios to learn how to assess readiness, proactively improve your architecture, react quickly to events, troubleshoot issues, and implement effective observability practices. Also use AWS Countdown and the AWS Well-Architected Framework as the entry point reference frameworks to use generative AI services for operation. Through hands-on activities, learn strategies for debugging issues, detecting anomalies and incidents, and optimizing architectures to improve the resilience of your workloads. You must bring your laptop to participate.
Resilience for customers operating in regulated industries
In regulated industries like finance, healthcare, and telecom, resilient architecture is critical for compliance, security, and operational continuity. These sectors face strict regulations that demand robust data protection, disaster recovery, and uptime guarantees. A resilient architecture helps organizations maintain service availability, minimize downtime, and recover quickly from disruptions, safeguarding sensitive data and avoiding regulatory breaches. It also enables businesses to adapt to evolving regulations while delivering secure, uninterrupted services.
Breakout sessions
Fidelity Investments: Building for mission-critical resilience (FSI318)
This session explores the transformation of Fidelity Investments’s trade processing platform on AWS and the critical role resiliency plays in preserving operational integrity.
Service event replay: Stress-testing your architecture’s resilience (FSI314)
Learn how to assess the resiliency of your own architectures and develop strategies to strengthen your response and recovery capabilities.
Workshops
Scaling multi-tenant SaaS with a cell-based architecture (ARC402)
In this workshop, see how cell-based architectures provide you with new ways to group, deploy, scale, and operate your multi-tenant workloads. Also see how this approach influences the tiering, scaling, and resilience profile of your SaaS architecture. You must bring your laptop to participate.
Advanced cross-Region DR patterns on AWS (ARC401)
Join this hands-on workshop to explore a resilient, cloud-centered architecture that surpasses the stringent availability and recovery regulations for financial markets utility providers. You must bring your laptop to participate.
Meet experts at the AWS Cloud Resilience kiosk
Throughout the re:Invent week, if you have any questions or suggestions for the AWS Cloud Resilience team, drop by the Cloud Resilience kiosk at the AWS Village in the 2024 re:Invent Expo (the Venetian).
This post was copyedited for grammar, spelling, capitalization, punctuation, terminology, and legal issues. Other important issues are noted in comments, and you should consider revising the content accordingly before publication.
Using zonal shift with Amazon EC2 Auto Scaling
Post Syndicated from aostan original https://aws.amazon.com/blogs/compute/using-zonal-shift-with-amazon-ec2-auto-scaling/
This post is written by Michael Haken, Senior Principal Solutions Architect, AWS
Today, we’re announcing support for zonal shift in Amazon EC2 Auto Scaling. Zonal shift gives allows you to rapidly recover from application impairments in a single Availability Zone (AZ) impacting your Auto Scaling Group (ASG) resources. In this post, we describe how performing an ASG zonal shift fits in to a multi-AZ resilience strategy and considerations for how to use the feature with different architectures.
Overview
Using multiple AZs is an architectural best practice for building resilient applications on AWS. Deploying your application across multiple AZs makes your applications more available, fault tolerant, and scalable. EC2 Auto Scaling enables you to further enhance your application’s availability and fault tolerance by dynamically scaling your Amazon Elastic Compute Cloud (Amazon EC2) instances across multiple AZs and replacing them when they’re unhealthy.
AZs in AWS represent a fault isolation boundary, meaning that failures from various sources are contained to a single AZ, whether caused by a bad deployment, networking issues, power loss, or operator error. In 2023, we launched zonal shift, part of Amazon Application Recovery Controller (ARC), which allows you to Rapidly recover from application impairments in a single AZ by shifting traffic at your Elastic Load Balancing (ELB) load balancer.
Zonal shift for EC2 Auto Scaling enhances this capability for users who have already implemented recovery patterns for single AZ impairments. It also provides recovery capabilities for architectures that aren’t load balanced by allowing you to prevent new instance launches in a specified AZ. Without zonal shift, when EC2 Auto Scaling detects consistent launch failures in an AZ, the service tries to launch instances in other AZs configured for the ASG. However, certain conditions, like gray failures, can cause post-launch problems in a single AZ that EC2 Auto Scaling doesn’t detect. For example, successfully launched instances in a single AZ experience elevated error rates downloading their configuration files over a zonal Amazon S3, Amazon Virtual Private Cloud (Amazon VPC) interface endpoint. The instances can’t correctly configure their application software and respond to requests with errors. Alternatively, the single-AZ impairment could cause the instance to fail its health checks after provisioning. This causes EC2 Auto Scaling to constantly recycle instances in the impaired AZ, leading to the application running with less capacity than desired.
Although you might choose to perform a zonal shift at your load balancer to mitigate the impact caused by the event, new instances can still be launched in the impacted AZ and don’t receive incoming requests. Even if your application architecture doesn’t use load balancers, zonal shift for EC2 Auto Scaling can help you recover from single-AZ impairments by allowing you to prevent instance launches in the impaired AZ.
Using EC2 Auto Scaling zonal shift to recover
To use zonal shift on your ASG, you need to configure it with an AvailabilityZoneImpairmentPolicy parameter either when you create a new ASG or update an existing one. This parameter has two options, ZonalShiftEnabled that enables or disables the ability to perform zonal shifts, and ImpairedZoneHealthCheckBehaviour. The latter option allows you to choose between ignoring or replacing instances identified as unhealthy by EC2 Auto Scaling. First, we look at how you can use zonal shift with a standalone ASG architecture.
Standalone ASG zonal shift
This architecture uses a standalone ASG without being integrated with an ELB load balancer. Workloads with a standalone ASG commonly perform event driven work such as generating load against a target based on a schedule or processing messages from a queue. The architecture in the following figure uses an ASG that reads messages from an Amazon Simple Queue Service (Amazon SQS) queue, performs some processing on the message data, and writes the results into an Amazon Aurora database. The instances communicate with Amazon SQS using a VPC endpoint in each AZ. Each message varies in size, thus the instances use a heartbeat pattern to update the message visibility timeout until they finish processing it. EC2 Auto Scaling scales instances based on the queue depth, which helps make sure that messages are processed in a timely manner.

Figure 1: EC2 instances deployed across three AZs that process messages from an SQS queue
Say that a networking degradation causes instances in AZ 1 to experience elevated error rates when attempting to write to the Aurora database, resulting in a 2x increase in the p50 processing latency. The instances in AZ 1 continue to heartbeat until they time out, keeping the message hidden and preventing other healthy instances from taking over the work. As a result, the queue depth grows and EC2 Auto Scaling deploys a new instance, as shown in the following figure.

Figure 2: EC2 Auto Scaling launches a new instance in AZ 1 in response to the queue depth growing
The new instance lands in AZ 1 and experiences the same problem as the other instance, thus it can’t decrease the queue depth and processing latency. Instead, it exacerbates the issue by consuming additional messages that aren’t successfully processed. The instances in AZ 1 never appeared unhealthy, thus EC2 Auto Scaling didn’t take any actions to replace them. To mitigate this problem, you can start a zonal shift for your ASG. This makes sure that any future instance launches only happen in AZ 2 or AZ 3, as shown in the following figure.

Figure 3: After the zonal shift new instances are only launched in AZ 2 and AZ 3 by EC2 Auto Scaling
You have the option to mark the instances as unhealthy using the SetInstanceHealth API to force EC2 Auto Scaling to replace these instances to prevent them from continuing to contribute to additional latency and errors. Changing the instance health state is considered a mutating change and relies on the EC2 Auto Scaling control plane. Therefore, you should avoid making this a critical step in your recovery plan. When you are confident that the impairment has abated, you can cancel the zonal shift, which causes EC2 Auto Scaling to automatically rebalance capacity across your AZs.
ASG with ELB zonal shift
In this section we observe how to use zonal shift with an ASG that is serving traffic from an ELB. We also examine how the ImpairedZoneHealthCheckBehavior affects recovery in this situation. In this architecture, the instances in the ASG read data from the database when they receive HTTP requests from the ELB, as shown in the following figure.

Figure 4: A three-tier application deployed in three AZs using an ALB, ASG, and Aurora database
In this scenario, the instances in AZ 1 start experiencing increased latency with their EBS volumes causing them to respond to requests with errors and fail their EC2 instance status checks. Initially, to mitigate the impact, you can start a zonal shift at your load balancer to prevent your users from receiving errors. Then, you can initiate a zonal shift for your ASG to prevent new capacity from being launched into the AZ that isn’t receiving traffic.
If the ASG’s ImpairedZoneHealthCheckBehavior is set to IgnoreUnhealthy, then the instances in AZ 1 that are failing their health checks aren’t terminated by EC2 Auto Scaling, as shown in the following figure. This can be helpful if you’re pre-scaled to handle the loss of an AZ’s worth of capacity by not causing EC2 Auto Scaling to attempt to launch additional instances. It can also make recovery safer by leaving capacity in the AZ, thus when you end your load balancer zonal shift after the impairment ends, the AZ can immediately start receiving traffic again.

Figure 5: Performing a zonal shift on the ALB and ASG, choosing to ignore unhealthy instances in the ASG
Alternatively, you can set the option to ReplaceUnhealthy. Now, instances that are found to be unhealthy by EC2 Auto Scaling are replaced. This option can be helpful if you aren’t pre-scaled to handle the loss of capacity. EC2 Auto Scaling launches new instances into the remaining AZs to bring the ASG back to its desired capacity, as shown in the following figure. However, this approach also has a tradeoff: launching new instances isn’t guaranteed to be successful, thus you might experience delays in acquiring new capacity.

Figure 6: Performing a zonal shift on the ALB and ASG, this time replacing unhealthy instances in the remaining AZs
In both situations you must consider whether you have cross-zone load balancing enabled or disabled. When cross-zone load balancing is enabled, each instance, regardless of its AZ, receives an approximately equal share of the traffic. This means that you can end your zonal shift for both your load balancer and ASG at the same time safely. As EC2 Auto Scaling rebalances your instances across each enabled AZ, they receive the same percentage of traffic.
If cross-zone load balancing is disabled, then each AZ receives an equal percentage of the traffic, regardless of how many instances are in the AZ. If you’ve chosen to replace unhealthy instances, or if your ASG has scaled during the event, then the capacity across your AZs could have become imbalanced. When you end your load balancer zonal shift and EC2 Auto Scaling begins to rebalance your capacity, you could end up in a situation shown in the following figure, where a single or small number of instances gets an overwhelming portion of the load.

Figure 7: A three-tier architecture with an imbalance of capacity among its three AZs
This imbalance can present an overload risk, thus you must specify the –skip-zonal-shift-validation parameter when you enable zonal shift to acknowledge that you understand the risk. However, you can help prevent overload from occurring due to imbalance by using the load balancer’s target_group_health.dns_failover.minimum_healthy_targets.count option and specifying the number of instances that should be present in the AZ. If you’re using three AZs and your desired capacity is 12, then you should set the value to four (which represents one third of the ASGs total capacity). This prevents traffic from being routed to the AZ until there is enough healthy capacity there to handle the load. You may need to dynamically adjust this number as the ASG scales over time. The minimum count you set in the past may not be the right minimum count today.
Zonal shift best practices
As a set of best practices, we recommend that you:
- Are pre-scaled to handle the loss of an AZ’s worth of capacity
- Configure your impairment policy to ignore unhealthy hosts
- Enable cross-zone load balancing
With this configuration, you can also safely use zonal autoshift. When zonal autoshift is enabled, AWS automatically starts and ends the zonal shift on your behalf whenever the AWS telemetry indicates there is an impairment affecting a single AZ. This can be used in conjunction with zonal autoshift for your ELB load balancer. If you are not using zonal autoshift, then you can still use the EventBridge observer notifications to inform your zonal shift decisions or start automated processes. Refer to the EC2 Auto Scaling zonal shift documentation for more details on the full set of best practices when using zonal shift.
Conclusion
In this post we showed you the benefits of using zonal shift with your Amazon EC2 Auto Scaling Groups as part of enhancing your resilience in multi-AZ architectures. We explored several scenarios where zonal shift can be used, and reviewed best practices for using zonal shift safely and effectively. To get started using zonal shift with your ASGs, refer to the documentation.
Streamline container application networking with built-in Amazon ECS support in Amazon VPC Lattice
Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/streamline-container-application-networking-with-native-amazon-ecs-support-in-amazon-vpc-lattice/
Since its launch, Amazon VPC Lattice has streamlined complex networking tasks. As a result, my perspective on how to build and connect modern, multi-service applications has changed. As my colleague Danilo wrote in his post announcing the general availability of VPC Lattice:
“By using VPC Lattice, you can focus on your application logic and improve productivity and deployment flexibility with consistent support for instances, containers, and serverless computing.”
Today, we’re announcing Amazon VPC Lattice built-in support for Amazon Elastic Container Service (Amazon ECS). With this new built-in integration, Amazon ECS services can now be directly associated with VPC Lattice target groups without the need for intermediate load balancers.
Here’s a quick look at how you can find Amazon VPC Lattice integration while creating an Amazon ECS service:

The Amazon VPC Lattice integration with Amazon ECS works by registering and deregistering IP addresses from ECS tasks within a service as targets in a VPC Lattice target group. As ECS tasks for the service are launched, Amazon ECS will automatically register those tasks to the VPC Lattice target group.
Furthermore, if ECS tasks fail VPC Lattice health checks, Amazon ECS will automatically replace the tasks. Also, if any task is terminated or scales down, it’s removed from the target group.
Using the Amazon VPC Lattice integration
Let me walk you through how to use this new integration. In the following demo, I will deploy a simple application server running as an ECS service and configure the integration with VPC Lattice. Then, I’ll test the application server by connecting to the VPC Lattice domain name without having to configure additional load balancers on Amazon ECS.
Before I can start with this integration, I need to make sure Amazon ECS will have the required permissions to register and deregister targets into VPC Lattice. To learn more, please visit the Amazon ECS infrastructure IAM role documentation page.
To use the integration with VPC Lattice, I need to define a task definition with at least one container and one port mapping. This is an example of my task definition.
{
    "containerDefinitions": [
        {
            "name": "webserver",
            "image": "public.ecr.aws/ecs-sample-image/amazon-ecs-sample:latest",
            "cpu": 0,
            "portMappings": [
                {
                    "name": "web-80-tcp",
                    "containerPort": 80,
                    "hostPort": 80,
                    "protocol": "tcp",
                    "appProtocol": "http"
                }
            ],
            ...
            *redacted for brevity*
}
Then, I navigate to my ECS cluster and choose Create.

Next, I need to select the task definition and assign the service name.

In the VPC Lattice integration section, I choose Turn on VPC Lattice to start configuring the target group for VPC Lattice. I don’t need to specify a load balancer because I’ll use VPC Lattice. By default, VPC Lattice will use a round-robin routing algorithm to route requests to healthy targets.

Now, I can start defining the integration for my ECS service in VPC Lattice. First, I select the infrastructure role for Amazon ECS. Then, I need to select the virtual private cloud (VPC) where I want my service to run. After that, I need to define the Target groups that will receive traffic. After I’m done configuring the service with VPC Lattice integration, I create this service.

After a few minutes, I have my ECS service ready. I navigate to the service and choose Configuration and networking. If I scroll down to the VPC Lattice section, I can see the VPC Lattice target group created.

To get more information on this target group, I select the target group name, which will redirect me to the VPC Lattice target group page. Here, I can see that Amazon ECS successfully registered the IP address of the running task.

Now, I need to create a VPC Lattice service and service network. My preference is always to create the VPC Lattice service then associate with the VPC Lattice service network later on. So, let’s do that.
I choose Services under the VPC Lattice section and choose Create service.

I fill in all the details required to create a VPC Lattice service and choose Next.

Then, I add a listener, and for the Forward to target group on the Listener default action, I select the newly created target group.

On the next page, because I’m going to create the VPC Lattice service network later, I skip this step and choose Next, review the configurations, and create the service.

With VPC Lattice service created, now it’s time to create VPC Lattice service networks. I navigate to Service networks under the VPC Lattice section and choose Create service network.

First, I fill the VPC Lattice service network name.

Then, on the Service associations page, I select the service that I have created.

I associate this service network to my VPC as well as the security group.

For the simplicity of this demo, I set None for the Auth type. However, I highly recommend you to read how you can use IAM to manage access to VPC Lattice. Then, I choose Create service network.

At this stage, we have everything setup for this integration. My VPC Lattice service network is now associated with my VPC Lattice service and my VPC.

With everything set up, I copy the Domain name from my VPC Lattice service page.

Then, to access the service, I log in to the instance in the same VPC and call the service by using the domain name from VPC Lattice.
[ec2-user@ ~]$ curl http://service-a-XYZ.XYZ.vpc-lattice-svcs.XYZ.on.aws

"Hello there! I'm Amazon ECS."
One thing to note is if you’re not receiving traffic to your Amazon ECS workloads, check the security groups as described in the Control traffic in VPC Lattice using security groups documentation page.
I’m personally excited about this integration because it unlocks various possibilities while streamlining application architectures and improving overall system reliability. Now that all AWS compute types are inherently supported in VPC Lattice, I can unify services across all my ECS clusters, AWS accounts, and VPCs.
Things to know
Here are a couple of important points to note:
- Availability – Amazon VPC Lattice integration with Amazon ECS is now available in AWS Regions where Amazon VPC Lattice and Amazon ECS are available.
- Compatibility – This integration supports all ECS launch types, including Amazon Elastic Compute Cloud (Amazon EC2) and AWS Fargate.
- Pricing – Standard VPC Lattice and Amazon ECS pricing applies. There are no additional charges for using this integration.
- Monitoring Amazon VPC Lattice – Check out Monitoring Amazon VPC Lattice in the VPC Lattice User Guide to learn how to monitor your Amazon VPC Lattice service networks, services, target groups, and VPC connections.
Try this new capability of Amazon VPC Lattice today and see how it can streamline your container application communication running on Amazon ECS.
Happy building!
Comic for 2024.11.18 – Dark Chocolate
Post Syndicated from Explosm.net original https://explosm.net/comics/dark-chocolate
New Cyanide and Happiness Comic
AWS Lambda SnapStart for Python and .NET functions is now generally available
Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-lambda-snapstart-for-python-and-net-functions-is-now-generally-available/
Today, we’re announcing the general availability of AWS Lambda SnapStart for Python and .NET functions that delivers faster function startup performance, from several seconds to as low as sub-second, typically with minimal or no code changes in Python, C#, F#, and Powershell.
In November 28, 2022, we introduced Lambda SnapStart for Java functions to improve startup performance by up to 10 times. With Lambda SnapStart, you can reduce outlier latencies that come from initializing functions, without having to provision resources or spend time implementing complex performance optimizations.
Lambda SnapStart works by caching and reusing the snapshotted memory and disk state of any one-time initialization code, or code that runs only the first time a Lambda function is invoked. Lambda takes a Firecracker microVM snapshot of the memory and disk state of the initialized execution environment, encrypts the snapshot, and caches it for low-latency access.

When you invoke the function version for the first time, and as the invocations scale up, Lambda resumes new execution environments from the cached snapshot instead of initializing them from scratch, improving startup latency. Lambda SnapStart makes it easy to build highly scalable and responsive applications in Python and .NET using AWS Lambda.
For Python functions, startup latency from initialization code can be several seconds long. Some scenarios where this can occur are – loading dependencies (such as LangChain, Numpy, Pandas, and DuckDB) or using frameworks (such as Flask or Django). Many functions also perform machine learning (ML) inference using Lambda, and need to load ML models during initialization – a process that can take tens of seconds depending on the size of the model used. Using Lambda SnapStart can reduce startup latency from several seconds to as low as sub-second for these scenarios.
For .NET functions, we expect most use cases to benefit because .NET just-in-time (JIT) compilation takes up to several seconds. Latency variability associated with initialization of Lambda functions has been a long-standing barrier for customers to use .NET for AWS Lambda. SnapStart enables functions to resume quickly by caching a snapshot of their memory and disk state. Therefore, most .NET functions will experience significant improvement in latency variability with Lambda SnapStart.
Getting started with Lambda SnapStart for Python and .NET
To get started, you can use the AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs to activate, update, and delete SnapStart for Python and .NET functions.
On the AWS Lambda console, go to the Functions page and choose your function to use Lambda SnapStart. Select Configuration, choose General configuration, and then choose Edit. You can see SnapStart settings on the Edit basic settings page.

You can activate Lambda functions using Python 3.12 and higher, and .NET 8 and higher managed runtimes. Choose Published versions and then choose Save.
When you publish a new version of your function, Lambda initializes your code, creates a snapshot of the initialized execution environment, and then caches the snapshot for low-latency access. You can invoke the function to confirm activation of SnapStart.
Here is an AWS CLI command to update the function configuration by running the update-function-configuration command with the --snap-start option.
aws lambda update-function-configuration \
  --function-name lambda-python-snapstart-test \
  --snap-start ApplyOn=PublishedVersions
Publish a function version with the publish-version command.
aws lambda publish-version \
  --function-name lambda-python-snapstart-test
Confirm that SnapStart is activated for the function version by running the get-function-configuration command and specifying the version number.
aws lambda get-function-configuration \
  --function-name lambda-python-snapstart-test:1
If the response shows that OptimizationStatus is On and State is Active, then SnapStart is activated, and a snapshot is available for the specified function version.
"SnapStart": {
    "ApplyOn": "PublishedVersions",
    "OptimizationStatus": "On"
 },
 "State": "Active",
To learn more about activating, updating, and deleting a snapshot with AWS SDKs, AWS CloudFormation, AWS Serverless Application Model (AWS SAM), and AWS Cloud Development Kit (AWS CDK), visit Activating and managing Lambda SnapStart in the AWS Lambda Developer Guide.
Runtime hooks
You can use runtime hooks to run code executed before Lambda creates a snapshot or after Lambda resumes a function from a snapshot. Runtime hooks are useful to perform cleanup or resource release operations, dynamically update configuration or other metadata, integrate with external services or systems, such as sending notifications or updating external state or to fine-tune your function’s startup sequence, such as by preloading dependencies.
Python runtime hooks are available as part of the open source Snapshot Restore for Python library, which is included in Python managed runtime. This library provides two decorators @register_before_snapshot to run before Lambda creates a snapshot and @register_after_restore to run when Lambda resumes a function from a snapshot. To learn more, visit Lambda SnapStart runtime hooks for Python in the AWS Lambda Developer Guide.
Here is an example Python handler to show how to run code before checkpointing and after restoring:
from snapshot_restore_py import register_before_snapshot, register_after_restore

def lambda_handler(event, context):
    # handler code

@register_before_snapshot
def before_checkpoint():
    # Logic to be executed before taking snapshots

@register_after_restore
def after_restore():
    # Logic to be executed after restore
You can also use .NET runtime hooks available as part of the Amazon.Lambda.Core package (version 2.5 or later) from NuGet. This library provides two methods RegisterBeforeSnapshot() to run before snapshot creation and RegisterAfterRestore() to run after resuming a function from a snapshot. To learn more, visit Lambda SnapStart runtime hooks for .NET in the AWS Lambda Developer Guide.
Here is an example C# handler to show how to run code before checkpointing and after restoring:
public class SampleClass
{
    public SampleClass()
    {
        Amazon.Lambda.Core.SnapshotRestore.RegisterBeforeSnapshot(BeforeCheckpoint);
        Amazon.Lambda.Core.SnapshotRestore.RegisterAfterRestore(AfterRestore);
    }

    private ValueTask BeforeCheckpoint()
    {
        // Add logic to be executed before taking the snapshot
        return ValueTask.CompletedTask;
    }

    private ValueTask AfterRestore()
    {
        // Add logic to be executed after restoring the snapshot
        return ValueTask.CompletedTask;
    }

    public APIGatewayProxyResponse FunctionHandler(APIGatewayProxyRequest request, ILambdaContext context)
    {
        // INSERT business logic
        return new APIGatewayProxyResponse
        {
            StatusCode = 200
        };
    }
}
To learn how to implement runtime hooks for your preferred runtime, visit Implement code before or after Lambda function snapshots in the AWS Lambda Developer Guide.
Things to know
Here are some things that you should know about Lambda SnapStart:
- Handling uniqueness – If your initialization code generates unique content that is included in the snapshot, then the content will not be unique when it’s reused across execution environments. To maintain uniqueness when using SnapStart, you must generate unique content after initialization, such as if your code uses custom random number generation that doesn’t rely on built-in-libraries or caches any information such as DNS entries that might expire during initialization. To learn how to restore uniqueness, visit Handling uniqueness with Lambda SnapStart in the AWS Lambda Developer Guide.
- Performance tuning – To maximize the performance, we recommend that you preload dependencies and initialize resources that contribute to startup latency in your initialization code instead of in the function handler. This moves the latency associated with heavy class loading out of the invocation path, optimizing startup performance with SnapStart.
- Networking best practices –The state of connections that your function establishes during the initialization phase isn’t guaranteed when Lambda resumes your function from a snapshot. In most cases, network connections that an AWS SDK establishes automatically resume. For other connections, review the Maximize Lambda SnapStart performance in the AWS Lambda Developer Guide.
- Monitoring functions – You can monitor your SnapStart functions using Amazon CloudWatch log stream, AWS X-Ray active tracing, and accessing real-time telemetry data for extensions using the Telemetry API, Amazon API Gateway and function URL metrics. To learn more about differences for SnapStart functions, visit Monitoring for Lambda SnapStart in the AWS Lambda Developer Guide.
Now available
AWS Lambda SnapStart for Python and .NET functions are available today in US East (N. Virginia), US East (Ohio), US West (Oregon), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Europe (Frankfurt), Europe (Ireland), and Europe (Stockholm) AWS Regions.
With the Python and .NET managed runtimes, there are two types of SnapStart charges: the cost of caching a snapshot per function version that you publish with SnapStart enabled, and the cost of restoration each time a function instance is restored from a snapshot. So, delete unused function versions to reduce your SnapStart cache costs. To learn more, visit the AWS Lambda pricing page.
Give Lambda SnapStart for Python and .NET a try in the AWS Lambda console. To learn more, visit Lambda SnapStart page and send feedback through AWS re:Post for AWS Lambda or your usual AWS Support contacts.
— Channy
FreeBSD Foundation releases Bhyve and Capsicum security audit
Post Syndicated from jzb original https://lwn.net/Articles/998615/
The FreeBSD Foundation has announced
the release of a security
audit report conducted by security firm Synacktiv. The audit uncovered
a number of vulnerabilities:
Most of these vulnerabilities have been addressed through official FreeBSD
Project security advisories, which offer detailed information
about each vulnerability, its impact, and the measures implemented to
improve the security of FreeBSD systems. […]The audit uncovered 27 vulnerabilities and issues within various
FreeBSD subsystems. 7 issues were not exploitable and were robustness
or code quality improvements rather than immediate security concerns.
Build and modify apps using natural language with AWS App Studio, now generally available
Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/build-and-modify-apps-using-natural-language-with-aws-app-studio-now-generally-available/
Announced as preview in July, AWS App Studio is a generative AI-powered application development service that enables users to create applications using natural language, without the need for professional software development skills. In that post, I covered how AWS App Studio helps you build secure, scalable applications and eliminates operational overhead by fully managing each application.
App Studio empowers a new set of builders to create business applications. Whether you are an IT Project Manager, Data Engineer, Enterprise Architect, or Solution Architect, simply describe your requirements in natural language, within minutes, App Studio generates fully functional applications complete with multipage UIs, data models, and custom business logic.
Today, we’re excited to announce that AWS App Studio is now generally available in the US West (Oregon) and Europe (Ireland) AWS Regions.
Building on feedback from the preview, we are introducing several new features to enhance your app building experience:
- Modify your applications with natural language
- Add intelligence to your app with a new generative AI component
- Generate and add custom business logic with natural language
- Customize your app’s theme and style
Modify your applications with natural language
During the preview period, customers shared with us that they enjoy and appreciate generating fully functional applications using natural language prompts. However, the development journey usually doesn’t stop there, and they asked if they could extend or modify their apps using natural language.
Now, with App Studio, you can modify your applications using natural language. After you’ve generated your applications, you can now describe your desired changes and the assistant will propose updates for you to review. Upon confirmation, it will automatically make the change. This feature makes it even faster and easier to customize your application.
Let’s see how it works in my IT inventory management application that I built with App Studio.
With this new feature, I can chat with the assistant to modify my applications.

To modify my application, I can provide a prompt to add another feature to my app. In this case, I need to add another text input for the web URL to get details of requested hardware, and I need to another text area to store notes.

The generative AI assistant will then process my input and provide a proposal. I can review this proposal and select Confirm to proceed.

Then, the assistant will automatically add the components and modify my application.

Add intelligence to your app with a new generative AI component
We’re also introducing a new component to make it even easier to add generative AI capabilities such as text summarization, content generation, and file analysis to your applications.
There are two ways to use this feature. First, with my canvas open, I can select the Gen AI component and drag and drop it onto the canvas. Then, while selecting the component, I can use the assistant to customize it.

Another way is to use the assistant directly. Let’s say I need a feature to analyze repair notes and provide a summary to make it easier for me to review. I can type what I need in the chat box or use the suggested prompts.

Then, the assistant will process my input and provide a proposal. I can review the proposal and select Confirm to proceed.

App Studio will automatically add the required components. On the canvas, I see there’s a button that triggers an automation. If I need to change the underlying prompt, I can select the link that will redirect me to the respective automation.

Under the hood, the Gen AI component is powered by a new action step called Gen AI Prompt. This new component provides an easy way to modify the prompt and input parameters to customize the output generated by the large language model (LLM).

Here’s my published app with the newly added generative AI feature to summarize repair notes.

Generate and add custom business logic with natural language
I can also use the assistant to help me add custom business logic with JavaScript in my automation.
Let’s say that I need a custom business logic to calculate repair duration and notify my stakeholders through email. Here’s the multi-step automation that I created. To add the custom logic to my automation, I choose the JavaScript component and then drag and drop it into the right spot.

Next, I need to select the action and, in the Properties panel, I select the Expand editor icon.

With this feature, I can now generate JavaScript code with natural language. Here, I provide a prompt and App Studio generates the source code for me along with comments. This generated source code provides a foundation that I can customize to suit my requirements.

Next, I need to add the Send Email action into my automation to complete the flow.

Customize your app’s theme and style
Now, you can customize the look and feel of your application with App themes. With this feature, you can change the appearance of your application to Light mode or Dark mode. Additionally, you can specify custom colors for your app to match your company’s brand. To enable this feature, you need to turn on the Customize toggle.

Available today
Start building secure, intelligent, and scalable business applications with App Studio today. It’s free to build, and you’ll receive a 60-day (250 user hour) free trial.
Learn more about all these features and others in the AWS App Studio documentation and join the conversation in the #aws-app-studio channel in the AWS Developers Slack workspace.
Happy building,
— Donnie
AWS Lambda turns ten – looking back and looking ahead
Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/aws-lambda-turns-ten-the-first-decade-of-serverless-innovation/
 I have a very vague memory of a 2013-era meeting with my then-colleague Tim Wagner. The term serverless did not exist, but we chatted about various ways to allow developers to focus on code instead of on infrastructure. At some I recall throwing my arms skyward and indicating that it would be cool to simply toss the code into the air and have the cloud grab, store, and run it. After many more such meetings, Tim wrote a PRFAQ proposing that we build a platform that did just that, and in 2014 I was able to announce AWS Lambda – Run Code in the Cloud.
From Startup to Enterprise
It is often the case that startups, with no installed base to worry about and the need to innovate, are the first to take a chance on something new such as Lambda. While that certainly did happen, I was pleasantly surprised to find that established companies—up to and including enterprises—were just as quick to jump in. After a bit of experimentation, they quickly found ways to build event-driven applications that supported critical internal use cases. I took this as an early indicator that Lambda would be a success. It was easy to see how quickly our customers felt a new sense of empowerment: they could move from idea to implementation, and from there to realizing business value, more quickly than ever, while still building their systems in a scalable and composable way.
Today, over 1.5 million Lambda users collectively make tens of trillion function invocations per month. These customers use Lambda for file processing, stream processing (in conjunction with Amazon Kinesis and/or Amazon MSK), web applications, IoT backends, mobile backends (often using Amazon API Gateway and AWS Amplify as well) and to support and power many other use cases.
The First Decade of Serverless Innovation
 Let’s roll back the calendar and take a look at a few of the more significant Lambda launches of the past decade:
2014 – The preview launch of AWS Lambda ahead of AWS re:Invent 2014 with support for Node.js and the ability to respond to event triggers from S3 buckets, DynamoDB tables, and Kinesis streams.
2015 – General availability, use of Amazon Simple Notification Service (Amazon SNS) notifications as triggers, and support for Lambda functions written in Java.
2016 – Support for DynamoDB Streams, Support for Python, and an increase in the function duration to 5 minutes (this was later raised to 15 minutes). Access to resources in a VPC, the power to call Lambda functions from Amazon Aurora stored procedures, environment variables, and the Serverless Application Model. This year also saw the introduction of Step Functions, which gave you the power to compose multiple Lambda functions to build more complex applications.
2017 – Support for AWS X-Ray, launches of AWS SAM Local and the Serverless Application Repository.
2018 – Support for Amazon SQS as an event trigger, the power to Extend AWS CloudFormation with Lambda-powered macros, and the ability to write your Lambda functions in any programming language.
2019 – Support for provisioned concurrency to give you additional control over performance.
2020 – Access to Savings Plans to save up to 17%, the ability for Lambda functions to access a shared file system, support for AWS PrivateLink to access your functions over a private network, code signing, billing at 1 ms granularity, functions that can use up to 10 MB of memory and 6 vCPUs, and support for container images.
2021 – Amazon S3 Object Lambda to let you process data as it is being retrieved from S3, AWS Lambda Extensions, support for running Lambda functions on Graviton processors.
2022 – Support for up to 10 GB of ephemeral storage per function invocation, HTTPS endpoints for Lambda functions, and Lambda SnapStart to make function invocation faster and more predictable.
2023 – Amazon S3 Object Lambda support for CloudFront, response streaming, and 12x faster function scaling when handling an unpredictable volume of requests.
2024 -New controls to make it easier to capture and search your Lambda function logs, SnapStart support for Java functions that use the ARM64 architecture, recursive loop detection, a new console editor based on VS Code, and an enhanced local IDE experience. The last two launches were designed to improve the developer experience by making it easier to build, test, debug, and deploy Lambda functions.
Again, this is just a subset of what we have launched. If you want to find even more launches, check out the Lambda category tag and search the What’s New for Lambda.
The Next Decade of Serverless
From the start, the vision for severless has been about helping developers to move from idea to business value more quickly. With that in mind, here are a couple of trends that seem clear to me as I look at Lambda’s direction over the first decade:
Default Choice – The serverless model is definitely here to stay, and will likely become the default operating model over time.
Continued Shift Toward Composability – Over time I can see that serverless applications will continue to make increasing use of reusable, prebuilt components. Aided by AI-powered development tools, a lot of new code will focus on connecting exiting components together in new and powerful ways. This will also boost consistency and reliability across applications.
Automated, AI-Optimized Infrastructure Management– We have already seen that Lambda reduces the amount of time and effort needed for managing infrastructure. Going forward, I can see that Machine Learning and other forms of AI will help to optimize costs and performance by allocating resources optimally with minimal human intervention. Applications will run on infrastructure that is automated, self-healing, and fault tolerant.
Extensibility and Integration – As a consequence of the two previous items, applications should be able to grow and adapt to changing conditions more easily than ever.
Security – Automated infrastructure management, real-time monitoring and other forms of threat detection, and AI-assisted remediation will work together to make serverless applications even more secure.
Some Lambda Resources
If you are already using Lambda to build serverless apps, great! If you are ready to get started, here are some resources to help out:
Serverless Training – Enroll in the free Serverless Learning Plan to learn about serverless concepts, common patterns, and best practices. Read the Serverless Ramp-Up Guide, and look at our extensive (in both topic and language) selection of digital training courses and in-person classroom training:

Case Studies – Review the AWS Serverless Customer Success stories to learn how AWS customers are building and innovating with Lambda and other serverless technologies.
re:Invent 2024 Sessions -Browse the re:Invent 2024 Session Catalog to find nearly 200 sessions focused on Serverless Compute & Containers:

Podcast – Listen to Episode 137 (AWS Lambda: A Decade of Transformation) of the AWS Developers Podcast to hear Marc Brooker and Julian Wood discuss the origins, evolution, and impact of Lambda.
 New Books – Take a peek at some of the newest books on serverless development and architecture:
- Serverless Development on AWS: Building Enterprise-Scale Serverless Solutions
- Advanced AWS Lambda: Comprehensive Guide to Serverless Computing
- Building Modern Applications with Serverless
- Event-Driven Architecture with AWS Lambda and SNS
- Serverless Microservices with AWS
- Mastering Serverless Architectures with AWS Lambda
I hope that you have enjoyed this not-so-brief look at the past, present, and future of AWS Lambda. Leave me a comment and let me know what you think!
— Jeff;
El Capitan Towers Above the Top500 in a Big HPE and AMD Win
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/el-capitan-towers-above-the-top500-in-a-big-hpe-and-amd-win/
The newest Top500 list is out, and we have the former #1 supercomputer Frontier was dethroned. In this list, the Intel-powered Aurora supercomputer passed 1EF, but then El Capitan rose to take the #1 spot. This is a big win for HPE and AMD delivering a system at over 2 exaflops of FP64 performance. El […]
The post El Capitan Towers Above the Top500 in a Big HPE and AMD Win appeared first on ServeTheHome.
AWS Weekly Roundup: AWS BuilderCards at re:Invent 2024, AWS Community Day, Amazon Bedrock, vector databases, and more (Nov 18, 2024)
Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-buildercards-at-reinvent-2024-aws-community-day-amazon-bedrock-vector-databases-and-more-nov-18-2024/
This week, we wrapped up the final 2024 Latin America Amazon Web Services (AWS) Community Days of the year in Brazil, with multiple parallel events taking place. In Goiânia, we had Marcelo Palladino, senior developer advocate, and Marcelo Paiva, AWS Community Builder, as keynote speakers. Florianópolis feature Ana Cunha, senior developer advocate, and in Santiago de Chile, I had the honor to share the stage with Rossana Suarez, AWS Container Hero, as keynote speakers. These events, organized by communities for communities, provide opportunities to network, learn something new, and immerse yourself in the community. In a community, everyone grows together, and no one is left behind.

AWS Lambda celebrates its 10th anniversary, the service that introduced me to AWS and remains my favorite. Born from customer needs, it revolutionized cloud computing by allowing code execution without server management. Since its inception, documented in this LinkedIn post by Dr. Werner Vogels, Chief Technology Officer at Amazon.com, through the original PR/FAQ document, the service has grown significantly, introducing features such as 1ms billing precision and support for 10GB memory. Thank you AWS Lambda, here’s to many more anniversaries.
Amazon invests $110 million to support AI research at universities using Trainium chips. The initiative provides computing resources using AWS Trainium chips, enabling researchers to develop new AI architectures and machine learning innovations that will be open-sourced for broader advancement. Check out the Linkedin post by Matt Garman, CEO at AWS.
Last week’s launches
AWS BuilderCards second edition at re:Invent 2024 – Jeff Barr announced the launch of the second edition of AWS BuilderCards at re:Invent 2024. It includes improvements to the design and game mechanics, plus a new add-on pack on generative AI. Over 15,000 sets have been distributed at previous events, with excellent user feedback. They’ll be available for online purchase after re:Invent.

Amazon EventBridge announces up to 94% improvement in end-to-end latency for Event Buses – Amazon EventBridge has improved end-to-end latency for Event Buses by up to 94%, reducing average latency from 2235.23ms (measured in January 2023) to 129.33ms (measured in August 2024 at P99). This enhancement enables faster processing for time-sensitive applications such as fraud detection, industrial automation, and gaming across all AWS Regions where Amazon EventBridge is available, including the AWS GovCloud (US) Regions, at no additional cost to you.
Introducing resource control policies (RCPs), a new type of authorization policy in AWS Organizations – Resource control policies (RCPs), a new authorization policy in AWS Organizations. RCPs allow centralized control over maximum permissions granted to resources, complementing service control policies (SCPs) that control permissions for principals. RCPs can restrict external access to resources like Amazon Simple Storage Service (Amazon S3) buckets, enforcing a data perimeter across the organization.

Replicate changes from databases to Apache Iceberg tables using Amazon Data Firehose (in preview) – A new preview capability in Amazon Data Firehose that captures and replicates database changes to Apache Iceberg tables on Amazon S3. This feature supports PostgreSQL and MySQL databases, providing a simple solution to stream database updates without impacting performance. It automatically handles data partitioning and schema evolution, eliminating the need for complex ETL processes.
Amazon S3 now supports up to 1 million buckets per AWS account– Amazon S3 has increased its default bucket quota from 100 to 10,000 per AWS account. Customers can now request increases up to 1 million buckets. The first 2,000 buckets are free, with a small monthly fee applying thereafter for additional buckets.
Amazon Keyspaces (for Apache Cassandra) reduces prices by up to 75% – Amazon Keyspaces (for Apache Cassandra) announces significant price reductions of up to 75%. The service reduces on-demand mode pricing by up to 56% for single-region and 65% for multi-region usage. Time-to-live (TTL) delete prices are also reduced by 75%.
Centrally managing root access for customers using AWS Organizations – AWS Identity and Access Management (IAM) launches a new capability for centrally managing root access in AWS Organizations. This feature allows security teams to remove long-term root credentials from member accounts and use temporary, task-scoped root sessions for specific actions. The solution enhances security by eliminating permanent root credentials while maintaining the ability to perform necessary privileged operations.

Amazon DynamoDB reduces prices for on-demand throughput and global tables – Amazon DynamoDB announces significant price reductions, cutting on-demand mode throughput costs by 50% and global tables by up to 67%. Multi-region replicated writes now match single-region pricing. These changes make on-demand mode the recommended choice for most DynamoDB workloads.
Amazon Q Developer plugins for Datadog and Wiz now generally available – Amazon Q Developer now offers plugins for Datadog and Wiz services, allowing users to access these partners features directly through the AWS Console. Users can query information using natural language commands like @datadog or @wiz to get real-time updates and security insights.
Other AWS blog posts
Here are some additional projects and blog posts that you might find interesting:
Introducing Stable Diffusion 3.5 Large in Amazon SageMaker JumpStart – This powerful 8.1 billion parameter model enables high-quality, photorealistic image generation from text prompts. Customers can seamlessly deploy and use the model in Amazon SageMaker JumpStart, benefiting from Amazon SageMaker security and machine learning operations (MLOps) capabilities.

Transcribe, translate, and summarize live streams in your browser with AWS AI and generative AI services – This blog post explains how we developed a Chrome extension that uses AI services to enhance live streaming experiences. The extension use Amazon Transcribe, Amazon Translate, and Amazon Bedrock to provide real-time transcription, translation, and summarization of live streams directly in the browser. It supports over 50 languages for transcription and 75 for translation, making content globally accessible.

Simplify automotive damage processing with Amazon Bedrock and vector databases –This blog post presents a solution combining Amazon Bedrock and vector databases to streamline automotive damage assessment. The system uses AI to analyze vehicle damage images, provide cost estimates, and match with similar cases from existing datasets. It use Anthropic’s Claude 3 and Amazon Titan Multimodal Embeddings, for efficient, accurate processing.

Revolutionize trip planning with Amazon Bedrock and Amazon Location Service – Amazon Bedrock and Amazon OpenSearch Service vector databases combine to automate automotive damage assessment, using AI to analyze images and match them with historical data for accurate repair estimates.

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:
AWS Community Days – Join community-led conferences featuring technical discussions, workshops, and hands-on labs driven by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are scheduled for November 23 in Indonesia, and on December 14 in Kochi, India.
AWS re:Invent 2024 – Join us in Las Vegas to learn all things AWS. Our annual conference is the best—and fastest—way to grow your skills. If you can’t join us in person, you can attend virtually by registering at
Watch re:Invent online.
Watch re:Invent online.
Browse all upcoming AWS led in-person and virtual events and developer-focused events.
Create your AWS Builder ID and reserve your alias. Builder ID is a universal login credential that gives users access to AWS tools and resources, including over 600 free training courses, community features, and developer tools such as Amazon Q Developer beyond the AWS Management Console.
That’s all for this week. Check back next Monday for another Weekly Roundup!
Thanks to Odina Jacobs for the AWS Community Chile photo.
— Eli
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!