Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=3I2xGcHrZx0
[$] The RCU API, 2024 edition
Post Syndicated from corbet original https://lwn.net/Articles/988638/
Read-copy-update (RCU) is a synchronization mechanism that was added to the
Linux kernel in October 2002. RCU is most frequently used as a replacement
for reader-writer locking, but is also used in a
number of other ways. This article covers recent changes to the RCU
API; it was contributed by Paul McKenney, Boqun Feng, Frederic Weisbecker,
Joel Fernandes, Neeraj Upadhyay, and Uladzislau Rezki.
How CFM built a well-governed and scalable data-engineering platform using Amazon EMR for financial features generation
Post Syndicated from Julien Lafaye original https://aws.amazon.com/blogs/big-data/how-cfm-built-a-well-governed-and-scalable-data-engineering-platform-using-amazon-emr-for-financial-features-generation/
This post is co-written with Julien Lafaye from CFM.
Capital Fund Management (CFM) is an alternative investment management company based in Paris with staff in New York City and London. CFM takes a scientific approach to finance, using quantitative and systematic techniques to develop the best investment strategies. Over the years, CFM has received many awards for their flagship product Stratus, a multi-strategy investment program that delivers decorrelated returns through a diversified investment approach while seeking a risk profile that is less volatile than traditional market indexes. It was first opened to investors in 1995. CFM assets under management are now $13 billion.
A traditional approach to systematic investing involves analysis of historical trends in asset prices to anticipate future price fluctuations and make investment decisions. Over the years, the investment industry has grown in such a way that relying on historical prices alone is not enough to remain competitive: traditional systematic strategies progressively became public and inefficient, while the number of actors grew, making slices of the pie smaller—a phenomenon known as alpha decay. In recent years, driven by the commoditization of data storage and processing solutions, the industry has seen a growing number of systematic investment management firms switch to alternative data sources to drive their investment decisions. Publicly documented examples include the usage of satellite imagery of mall parking lots to estimate trends in consumer behavior and its impact on stock prices. Using social network data has also often been cited as a potential source of data to improve short-term investment decisions. To remain at the forefront of quantitative investing, CFM has put in place a large-scale data acquisition strategy.
As the CFM Data team, we constantly monitor new data sources and vendors to continue to innovate. The speed at which we can trial datasets and determine whether they are useful to our business is a key factor of success. Trials are short projects usually taking up to a several months; the output of a trial is a buy (or not-buy) decision if we detect information in the dataset that can help us in our investment process. Unfortunately, because datasets come in all shapes and sizes, planning our hardware and software requirements several months ahead has been very challenging. Some datasets require large or specific compute capabilities that we can’t afford to buy if the trial is a failure. The AWS pay-as-you-go model and the constant pace of innovation in data processing technologies enable CFM to maintain agility and facilitate a steady cadence of trials and experimentation.
In this post, we share how we built a well-governed and scalable data engineering platform using Amazon EMR for financial features generation.
AWS as a key enabler of CFM’s business strategy
We have identified the following as key enablers of this data strategy:
- Managed services – AWS managed services reduce the setup cost of complex data technologies, such as Apache Spark.
- Elasticity – Compute and storage elasticity removes the burden of having to plan and size hardware procurement. This allows us to be more focused on the business and more agile in our data acquisition strategy.
- Governance – At CFM, our Data teams are split into autonomous teams that can use different technologies based on their requirements and skills. Each team is the sole owner of its AWS account. To share data to our internal consumers, we use AWS Lake Formation with LF-Tags to streamline the process of managing access rights across the organization.
Data integration workflow
A typical data integration process consists of ingestion, analysis, and production phases.
CFM usually negotiates with vendors a download method that is convenient for both parties. We see a lot of possibilities for exchanging data (HTTPS, FPT, SFPT), but we’re seeing a growing number of vendors standardizing around Amazon Simple Storage Service (Amazon S3).
CFM data scientists then look up the data and build features that can be used in our trading models. The bulk of our data scientists are heavy users of Jupyter Notebook. Jupyter notebooks are interactive computing environments that allow users to create and share documents containing live code, equations, visualizations, and narrative text. They provide a web-based interface where users can write and run code in different programming languages, such as Python, R, or Julia. Notebooks are organized into cells, which can be run independently, facilitating the iterative development and exploration of data analysis and computational workflows.
We invested a lot in polishing our Jupyter stack (see, for example, the open source project Jupytext, which was initiated by a former CFM employee), and we are proud of the level of integration with our ecosystem that we have reached. Although we explored the option of using AWS managed notebooks to streamline the provisioning process, we have decided to continue hosting these components on our on-premises infrastructure for the current timeline. CFM internal users appreciate the existing development environment and switching to an AWS managed environment would imply a change to their habits, and a temporary drop in productivity.
Exploration of small datasets is entirely feasible within this Jupyter environment, but for large datasets, we have identified Spark as the go-to solution. We could have deployed Spark clusters in our data centers, but we have found that Amazon EMR considerably reduces the time to deploy said clusters and provides many interesting features, such as ARM support through AWS Graviton processors, auto scaling capabilities, and the ability to provision transient clusters.
After a data scientist has written the feature, CFM deploys a script to the production environment that refreshes the feature as new data comes in. These scripts often run in a relatively short amount of time because they only require processing a small increment of data.
Interactive data exploration workflow
CFM’s data scientists’ preferred way of interacting with EMR clusters is through Jupyter notebooks. Having a long history of managing Jupyter notebooks on premises and customizing them, we opted to integrate EMR clusters into our existing stack. The user workflow is as follows:
- The user provisions an EMR cluster through the AWS Service Catalog and the AWS Management Console. Users can also use API calls to do this, but usually prefer using the Service Catalog interface. You can choose various instance types that include different combinations of CPU, memory, and storage, giving you the flexibility to choose the appropriate mix of resources for your applications.
- The user starts their Jupyter notebook instance and connects to the EMR cluster.
- The user interactively works on the data using the notebook.
- The user shuts down the cluster through the Service Catalog.
Solution overview
The connection between the notebook and the cluster is achieved by deploying the following open source components:
- Apache Livy – This service that provides a REST interface to a Spark driver running on an EMR cluster.
- Sparkmagic – This set of Jupyter magics provides a straightforward way to connect to the cluster and send PySpark code to the cluster through the Livy endpoint.
- Sagemaker-studio-analytics-extension – This library provides a set of magics to integrate analytics services (such as Amazon EMR) into Jupyter notebooks. It is used to integrate Amazon SageMaker Studio notebooks and EMR clusters (for more details, see Create and manage Amazon EMR Clusters from SageMaker Studio to run interactive Spark and ML workloads – Part 1). Having the requirement to use our own notebooks, we initially didn’t benefit from this integration. To help us, the Amazon EMR service team made this library available on PyPI and guided us in setting it up. We use this library to facilitate the connection between the notebook and the cluster and to forward the user permissions to the clusters through runtime roles. These runtime roles are then used to access the data instead of instance profile roles assigned to the Amazon Elastic Compute Cloud (Amazon EC2) instances that are part of the cluster. This allows more fine-grained access control on our data.
The following diagram illustrates the solution architecture.

Set up Amazon EMR on an EC2 cluster with the GetClusterSessionCredentials API
A runtime role is an AWS Identity and Access Management (IAM) role that you can specify when you submit a job or query to an EMR cluster. The EMR get-cluster-session-credentials API uses a runtime role to authenticate on EMR nodes based on the IAM policies attached runtime role (we document the steps to enable for the Spark terminal; a similar approach can be expanded for Hive and Presto). This option is generally available in all AWS Regions and the recommended release to use is emr-6.9.0 or later.
Connect to Amazon EMR on the EC2 cluster from Jupyter Notebook with the GCSC API
Jupyter Notebook magic commands provide shortcuts and extra functionality to the notebooks in addition to what can be done with your kernel code. We use Jupyter magics to abstract the underlying connection from Jupyter to the EMR cluster; the analytics extension makes the connection through Livy using the GCSC API.
On your Jupyter instance, server, or notebook PySpark kernel, install the following extension, load the magics, and create a connection to the EMR cluster using your runtime role:
Production with Amazon EMR Serverless
CFM has implemented an architecture based on dozens of pipelines: data is ingested from data on Amazon S3 and transformed using Amazon EMR Serverless with Spark; resulting datasets are published back to Amazon S3.
Each pipeline runs as a separate EMR Serverless application to avoid resource contention between workloads. Individual IAM roles are assigned to each EMR Serverless application to apply least privilege access.
To control costs, CFM uses EMR Serverless automatic scaling combined with the maximum capacity feature (which defines the maximum total vCPU, memory, and disk capacity that can be consumed collectively by all the jobs running under this application). Finally, CFM uses an AWS Graviton architecture to optimize even more cost and performance (as highlighted in the screenshot below).

After some iterations, the user produces a final script that is put in production. For early deployments, we relied on Amazon EMR on EC2 to run those scripts. Based on user feedback, we iterated and investigated for opportunities to reduce cluster startup times. Cluster startups could take up to 8 minutes for a runtime requiring a fraction of that time, which impacted the user experience. Also, we wanted to reduce the operational overhead of starting and stopping EMR clusters.
Those are the reasons why we switched to EMR Serverless a few months after its initial release. This move was surprisingly straightforward because it didn’t require any tuning and worked instantly. The only drawback we have seen is the requirement to update AWS tools and libraries in our software stacks to incorporate all the EMR features (such as AWS Graviton); on the other hand, it led to reduced startup time, reduced costs, and better workload isolation.
At this stage, CFM data scientists can perform analytics and extract value from raw data. Resulting datasets are then published to our data mesh service across our organization to allow our scientists to work on prediction models. In the context of CFM, this requires a strong governance and security posture to apply fine-grained access control to this data. This data mesh approach allows CFM to have a clear view from an audit standpoint on dataset usage.
Data governance with Lake Formation
A data mesh on AWS is an architectural approach where data is treated as a product and owned by domain teams. Each team uses AWS services like Amazon S3, AWS Glue, AWS Lambda, and Amazon EMR to independently build and manage their data products, while tools like the AWS Glue Data Catalog enable discoverability. This decentralized approach promotes data autonomy, scalability, and collaboration across the organization:
- Autonomy – At CFM, like at most companies, we have different teams with difference skillsets and different technology needs. Enabling teams to work autonomously was a key parameter in our decision to move to a decentralized model where each domain would live in its own AWS account. Another advantage was improved security, particularly the ability to contain the potential impact area in the event of credential leaks or account compromises. Lake Formation is key in enabling this kind of model because it streamlines the process of managing access rights across accounts. In the absence of Lake Formation, administrators would have to make sure that resource policies and user policies align to grant access to data: this is usually considered complex, error-prone, and hard to debug. Lake Formation makes this process a lot less complicated.
- Scalability – There are no blockers that prevent other organization units from joining the data mesh structure, and we expect more teams to join the effort of refining and sharing their data assets.
- Collaboration – Lake Formation provides a sound foundation for making data products discoverable by CFM internal consumers. On top of Lake Formation, we developed our own Data Catalog portal. It provides a user-friendly interface where users can discover datasets, read through the documentation, and download code snippets (see the following screenshot). The interface is tailor-made for our work habits.

Lake Formation documentation is extensive and provides a collection of ways to achieve a data governance pattern that fits every organization requirement. We made the following choices:
- LF-Tags – We use LF-Tags instead of named resource permissioning. Tags are associated to resources, and personas are given the permission to access all resources with a certain tag. This makes scaling the process of managing rights straightforward. Also, this is an AWS recommended best practice.
- Centralization – Databases and LF-Tags are managed in a centralized account, which is managed by a single team.
- Decentralization of permissions management – Data producers are allowed to associate tags to the datasets they are responsible for. Administrators of consumer accounts can grant access to tagged resources.
Conclusions
In this post, we discussed how CFM built a well-governed and scalable data engineering platform for financial features generation.
Lake Formation provides a solid foundation for sharing datasets across accounts. It removes the operational complexity of managing complex cross-account access through IAM and resource policies. For now, we only use it to share assets created by data scientists, but plan to add new domains in the near future.
Lake Formation also seamlessly integrates with other analytics services like AWS Glue and Amazon Athena. The ability to provide a comprehensive and integrated suite of analytics tools to our users is a strong reason for adopting Lake Formation.
Last but not least, EMR Serverless reduced operational risk and complexity. EMR Serverless applications start in less than 60 seconds, whereas starting an EMR cluster on EC2 instances typically takes more than 5 minutes (as of this writing). The accumulation of those earned minutes effectively eliminated any further instances of missed delivery deadlines.
If you’re looking to streamline your data analytics workflow, simplify cross-account data sharing, and reduce operational overhead, consider using Lake Formation and EMR Serverless in your organization. Check out the AWS Big Data Blog and reach out to your AWS team to learn more about how AWS can help you use managed services to drive efficiency and unlock valuable insights from your data!
About the Authors
 Julien Lafaye is a director at Capital Fund Management (CFM) where he is leading the implementation of a data platform on AWS. He is also heading a team of data scientists and software engineers in charge of delivering intraday features to feed CFM trading strategies. Before that, he was developing low latency solutions for transforming & disseminating financial market data. He holds a Phd in computer science and graduated from Ecole Polytechnique Paris. During his spare time, he enjoys cycling, running and tinkering with electronic gadgets and computers.
 Matthieu Bonville is a Solutions Architect in AWS France working with Financial Services Industry (FSI) customers. He leverages his technical expertise and knowledge of the FSI domain to help customer architect effective technology solutions that address their business challenges.
 Joel Farvault is Principal Specialist SA Analytics for AWS with 25 years’ experience working on enterprise architecture, data governance and analytics, mainly in the financial services industry. Joel has led data transformation projects on fraud analytics, claims automation, and Master Data Management. He leverages his experience to advise customers on their data strategy and technology foundations.
Tyan GC70-B8033 1U AMD EPYC Milan Server Review
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/tyan-gc70-b8033-bs8033g70e2hr-c-1u-amd-epyc-milan-review-mitac-kioxia-intel-marvell/
In our Tyan GC70-B8033 review, we find a really neatly designed AMD EPYC Milan 1U server designed for easy service with unique features
The post Tyan GC70-B8033 1U AMD EPYC Milan Server Review appeared first on ServeTheHome.
Experience AI: How research continues to shape the resources
Post Syndicated from Lou Loxley original https://www.raspberrypi.org/blog/experience-ai-how-research-continues-to-shape-the-resources/
Since we launched the Experience AI learning programme in the UK in April 2023, educators in 130 countries have downloaded Experience AI lesson resources. They estimate reaching over 630,000 young people with the lessons, helping them to understand how AI works and to build the knowledge and confidence to use AI tools responsibly. Just last week, we announced another exciting expansion of Experience AI: thanks to $10 million in funding from Google.org, we will be able to work with local partner organisations to provide research-based AI education to an estimated over 2 million young people across Europe, the Middle East and Africa.
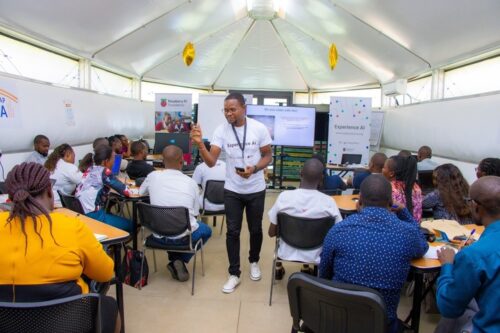
This blog post explains how we use research to continue to shape our Experience AI resources, including the new AI safety resources we are developing.
The beginning of Experience AI
Artificial intelligence (AI) and machine learning (ML) applications are part of our everyday lives — we use them every time we scroll through social media feeds organised by recommender systems or unlock an app with facial recognition. For young people, there is more need than ever to gain the skills and understanding to critically engage with AI technologies.
We wanted to design free lesson resources to help teachers in a wide range of subjects confidently introduce AI and ML to students aged 11 to 14 (Key Stage 3). This led us to develop Experience AI, in collaboration with Google DeepMind, offering materials including lesson plans, slide decks, videos (both teacher- and student-facing), student activities, and assessment questions.
SEAME: The research-based framework behind Experience AI
The Experience AI resources were built on rigorous research from the Raspberry Pi Computing Education Research Centre as well as from other researchers, including those we hosted at our series of seminars on AI and data science education. The Research Centre’s work involved mapping and categorising over 500 resources used to teach AI and ML, and found that the majority were one-off activities, and that very few resources were tailored to a specific age group.
To analyse the content that existing AI education resources covered, the Centre developed a simple framework called SEAME. The framework gives you an easy way to group concepts, knowledge, and skills related to AI and ML based on whether they focus on social and ethical aspects (SE), applications (A), models (M), or engines (E, i.e. how AI works.)
Through Experience AI, learners also gain an understanding of the models underlying AI applications, and the processes used to train and test ML models.
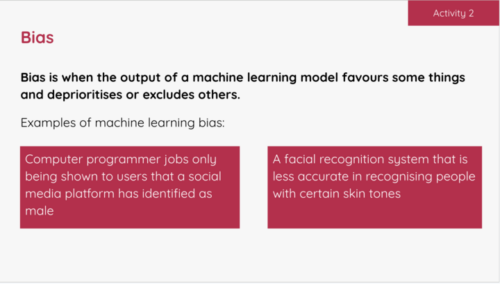
Our Experience AI lessons cover all four levels of SEAME and focus on applications of AI that are relatable for young people. They also introduce learners to AI-related issues such as privacy or bias concerns, and the impact of AI on employment.
The six foundation lessons of Experience AI
- What is AI?: Learners explore the current context of AI and how it is used in the world around them. Looking at the differences between rule-based and data-driven approaches to programming, they consider the benefits and challenges that AI could bring to society.
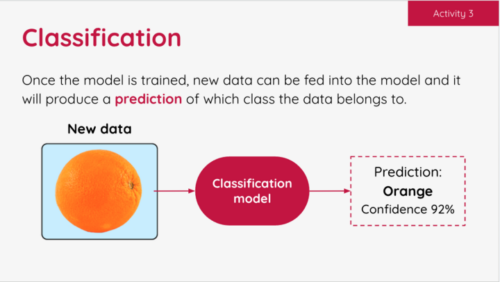
- How computers learn: Focusing on the role of data-driven models in AI systems, learners are introduced to ML and find out about three common approaches to creating ML models. Finally they explore classification, a specific application of ML.
- Bias in, bias out: Students create their own ML model to classify images of apples and tomatoes. They discover that a limited dataset is likely to lead to a flawed ML model. Then they explore how bias can appear in a dataset, resulting in biased predictions produced by a ML model.
- Decision trees: Learners take their first in-depth look at a specific type of ML model: decision trees. They see how different training datasets result in the creation of different ML models, experiencing first-hand what the term ‘data-driven’ means.
- Solving problems with ML models: Students are introduced to the AI project lifecycle and use it to create a ML model. They apply a human-focused approach to working on their project, train a ML model, and finally test their model to find out its accuracy.
- Model cards and careers: Learners finish the AI project lifecycle by creating a model card to explain their ML model. To complete the unit, they explore a range of AI-related careers, hear from people working in AI research at Google DeepMind, and explore how they might apply AI and ML to their interests.
We also offer two additional stand-alone lessons: one on large language models, how they work, and why they’re not always reliable, and the other on the application of AI in ecosystems research, which lets learners explore how AI tools can be used to support animal conservation.
New AI safety resources: Empowering learners to be critical users of technology
We have also been developing a set of resources for educator-led sessions on three topics related to AI safety, funded by Google.org.
- AI and your data: With the support of this resource, young people reflect on the data they have already provided to AI applications in their daily lives, and think about how the prevalence of AI tools might change the way they protect their data.
- Media literacy in the age of AI: This resource highlights the ways AI tools can be used to perpetuate misinformation and how AI applications can help people combat misleading claims.
- Using generative AI responsibly: With this resource, young people consider their responsibilities when using generative AI, and their expectations of developers who release Experience AI tools.
Other research principles behind our free teaching resources
As well as using the SEAME framework, we have incorporated a whole host of other research-based concepts in the design principles for the Experience AI resources. For example, we avoid anthropomorphism — that is, words or imagery that can lead learners to wrongly believe that AI applications have sentience or intentions like humans do — and we instead promote the understanding that it’s people who design AI applications and decide how they are used. We also teach about data-driven application design, which is a core concept in computational thinking 2.0.
Share your feedback
We’d love to hear your thoughts and feedback about using the Experience AI resources. Your comments help us to improve the current materials, and to develop future resources. You can tell us what you think using this form.
And if you’d like to start using the Experience AI resources as an educator, you can download them for free at experience-ai.org.
The post Experience AI: How research continues to shape the resources appeared first on Raspberry Pi Foundation.
Reduce risks of user sign-up fraud and SMS pumping with Amazon Cognito user pools
Post Syndicated from Edward Sun original https://aws.amazon.com/blogs/security/reduce-risks-of-user-sign-up-fraud-and-sms-pumping-with-amazon-cognito-user-pools/
If you have a customer facing application, you might want to enable self-service sign-up, which allows potential customers on the internet to create an account and gain access to your applications. While it’s necessary to allow valid users to sign up to your application, self-service options can open the door to unintended use or sign-ups. Bad actors might leverage the user sign-up process for unintended purposes, launching large-scale distributed denial of service (DDoS) attacks to disrupt access for legitimate users or committing a form of telecommunications fraud known as SMS pumping. SMS pumping is when bad actors purchase a block of high-rate phone numbers from a telecom provider and then coerces unsuspecting services into sending SMS messages to those numbers.
Amazon Cognito is a managed OpenID Connect (OIDC) identity provider (IdP) that you can use to add self-service sign-up, sign-in, and control access features to your web and mobile applications. AWS customers who use Cognito might encounter SMS pumping if SMS functions are enabled to send SMS messages, for example, perform user phone number verification during the registration process, to facilitate SMS multi-factor authentication (MFA) flows, or to support account recovery using SMS. In this blog post, we explore how SMS pumping may be perpetrated and options to reduce risks, including blocking unexpected user registration, detecting anomalies, and responding to risk events with your Cognito user pool.
Cognito user sign-up process
After a user has signed up in your application with an Amazon Cognito user pool, their account is placed in the Registered (unconfirmed) state in your user pool and the user won’t be able to sign in yet. You can use the Cognito-assisted verification and confirmation process to verify user-provided attributes (such as email or phone number) and then confirm the user’s status. This verified attribute is also used for MFA and account recovery purposes. If you choose to verify the user’s phone number, Cognito sends SMS messages with a one-time password (OTP). After a user has provided the correct OTP, their email or phone number is marked as verified and the user can sign in to your application.

Figure 1: Amazon Cognito sign-up process
If the sign-up process isn’t protected, bad actors can create scripts or deploy bots to sign up a large number of accounts, resulting in a significant volume of SMS messages sent in a short period of time. We dive deep into prevention, detection, and remediation mechanisms and strategies that you can apply to help protect against SMS pumping based on your use case.
Protect the sign-up flow
In this section, we review several prevention strategies to help protect against SMS sign-up frauds and help reduce the amount of SMS messages sent to bad actors.
Implement bot mitigation
Implementing bot mitigation techniques, such as CAPTCHA, can be very effective in preventing simple bots from pumping user creation flows. You can integrate a CAPTCHA framework on your application’s frontend and validate that the client initiating the sign-up request is operated by a human user. If the user has passed the verification, you then pass the CAPTCHA user response token in ClientMetadata together with user attributes to an Amazon Cognito SignUp API call. As part of the sign-up process, Cognito invokes an AWS Lambda function called pre sign-up Lambda trigger, which you can use to reject sign-up requests if there isn’t a valid CAPTCHA token presented. This will slow down bots and help reduce unintended account creation in your Cognito user pool.
Validate phone number before user sign-up
Another layer of mitigation is to identify the actor’s phone number early in your application’s sign-up process. You can validate the user provided phone number in the backend to catch incorrectly formatted phone numbers and add logic to help filter out unwanted phone numbers prior to sending text messages. Amazon Pinpoint offers a Phone Number Validate feature that can help you determine if a user-provided phone number is valid, determine phone number type (such as mobile, landline, or VoIP), and identify the country and service provider the phone number is associated with. The returned phone number metadata can be used to decide whether the user will continue the sign-up process and send an SMS message to that user. Note that there’s an additional charge for using the phone number validation service. For more information, see Amazon Pinpoint pricing.
To build this validation check into the Amazon Cognito sign-up process, you can customize the pre sign-up Lambda trigger, which Cognito uses to invoke your code before allowing users to sign-up and sending out an SMS OTP. The Lambda trigger invokes the Amazon Pinpoint phone number validate API, and based on the validation response, you can build a custom pattern that fits your application to continue or reject the user sign-up. For example, you can reject user sign-ups with VoIP numbers or reject users who provide a phone number that’s associated with countries that you don’t operate in, or even reject certain cellular service providers. After you reject a user sign-up using the Lambda trigger, Cognito will deny the user sign-up request and will not invoke user confirmation flow nor send out an SMS message.
Example validation command using AWS CLI
When you send a request to the Amazon Pinpoint phone number validation service, it returns the following metadata about the phone number. The following example represents a valid mobile phone number data set:
{
    "NumberValidateResponse": {
        "Carrier": "ExampleCorp Mobile",
        "City": "Seattle",
        "CleansedPhoneNumberE164": "+155501001234",
        "CleansedPhoneNumberNational": "55501001234",
        "Country": "United States",
        "CountryCodeIso2": "US",
        "CountryCodeNumeric": "1",
        "OriginalPhoneNumber": "+155501001234",
        "PhoneType": "MOBILE",
        "PhoneTypeCode": 0,
        "Timezone": "America/Seattle",
        "ZipCode": "98109"
    }
}
Note that PhoneType includes type MOBILE, LANDLINE, VOIP, INVALID, or OTHER. INVALID phone numbers don’t include information about the carrier or location associated with the phone number and are unlikely to belong to actual recipients. This helps you decide when to reject user sign-ups and reduces SMS messages to undesired phone numbers. You can see details about other responses in the Amazon Pinpoint developer guide.
Example pre sign-up Lambda function to block user sign-up except with a valid MOBILE number
The following pre sign-up Lambda function example invokes the Amazon Pinpoint phone number validation service and rejects user sign-ups unless the validation service returns a valid mobile phone number.
import { PinpointClient, PhoneNumberValidateCommand } from "@aws-sdk/client-pinpoint"; // ES Modules import

const validatePhoneNumber = async (phoneNumber) => {
  const pinpoint = new PinpointClient();
  const input = { // PhoneNumberValidateRequest
    NumberValidateRequest: { // NumberValidateRequest
      PhoneNumber: phoneNumber,
    },
  };
  const command = new PhoneNumberValidateCommand(input);
  const response = await pinpoint.send(command);

  return response;
};

const handler = async (event, context, callback) => {

  const phoneNumber = event.request.userAttributes.phone_number;
  const validationResponse = await validatePhoneNumber(phoneNumber);

  if (validationResponse.NumberValidateResponse.PhoneType != "MOBILE") {
    var error = new Error("Cannot register users without a mobile number");
    // Return error to Amazon Cognito
    callback(error, event);
  }
  // Return to Amazon Cognito
  callback(null, event);
};

export { handler };
Use a custom user-initiated confirmation flow or alternative OTP delivery method
In your user pool configurations, you can opt out of using Amazon Cognito-assisted verification and confirmation to send SMS messages to confirm users. Instead, you can build a custom reverse OTP flow to ask your users to initiate the user confirmation process. For example, instead of automatically sending SMS messages to a user when they sign up, your application can display an OTP and direct the user to initiate the SMS conversation by texting the OTP to your service number. After your application has received the SMS message and confirmed the correct OTP is provided, invoke a service such as a Lambda function to call the AdminConfirmSignUp administrative API operation to confirm user, then call AdminUpdateUserAttributes to set the phone_number_verified attribute as true to indicate that the user phone number is verified.
You can also choose to deliver an OTP using other methods, such as email, especially if your application doesn’t require the user’s phone number. During the user sign-up process, you can configure a custom SMS sender Lambda trigger in Amazon Cognito to send a user verification code through email or another method. Additionally, you can use the Cognito email MFA feature to send MFA codes through email.
Detect SMS pumping
When you’re considering the various prevention options, it’s important to set up detection mechanisms to identify SMS pumping as they arise. In this section, we show you how to use AWS CloudTrail and Amazon CloudWatch to monitor your Amazon Cognito user pool and detect anomalies that could lead to SMS pumping. Note that building detection mechanism based on anomalies requires knowing your average or baseline traffic and the difference in metrics that represent regular activity and metrics that can indicate unauthorized or unintended activity.
Service quotas dashboard and CloudWatch alarms
Bad actors may attempt to leverage either the sign-up confirmation or the reset password functionality of Amazon Cognito. As shown previously in Figure 1, when a new user signs up to your Cognito user pool, the SignUp API operation is invoked. When the user provides the OTP confirmation code, the ConfirmSignUp API operation is invoked. The call rate of both APIs is tracked collectively under Rate of UserCreation requests under Amazon Cognito service in the service quotas dashboard.
You can set up Amazon CloudWatch alarms to monitor and issue notifications when you’re close to a quota value threshold. These alarms could be an early indication of a sudden usage increase, and you can use them to triage potential incidents.
Additionally, when your services are sending SMS messages, those transactions count towards the Amazon Simple Notification Service (Amazon SNS) service quota. You should set up alarms to monitor the Transactional SMS Message Delivery Rate per Second quota and the SMS Message Spending in USD quota.
CloudTrail event history
When bad actors plan SMS pumping, they are likely attempting to trick you to send as many SMS messages as possible rather than completing the user confirmation process. Under the context of a user sign-up event, you might notice in the CloudTrail event history that there are more SignUp and ResendConfirmationCode events—which send out SMS messages—than ConfirmSignUp operations; indicating a user has initiated but not completed the sign-up process. You can use Amazon Athena or CloudWatch Logs Insights to search and analyze your Amazon Cognito CloudTrail events and identify if there’s a significant reduction in finishing the user sign-up process.

Figure 2: SignUp API logged in CloudTrail event history
Similarly, you can apply this observability towards the user password reset flow by analyzing the ForgotPassword API and ConfirmForgotPassword API operations for deviations.
Note that the slight deviations in user completion flow in the CloudTrail event history alone might not be an indication of unauthorized activity, however a substantial deviation above the regular baseline might be a signal of unintended use.
Monitor excessive billing
Another opportunity for detecting and identifying unauthorized Amazon Cognito activity is by using AWS Cost Explorer. You can use this interface to visualize, understand, and manage your AWS costs and usage over time, which might assist by highlighting the source of excessive billing in your AWS account. Be aware that charges in your account can take up to 24 hours to be displayed, so while this method can help provide some assistance in identifying SMS pumping activity, it should only be used as a supplement to other detection methods.
To use Cost Explorer:
- Open the AWS Management Console, and go to Billing and Cost Management.
- In the navigation pane, under Cost Analysis, choose Cost Explorer.
- In the Cost and Usage Report, under Report Parameters, select Date Range to include the start and end date of the time period that you want to apply a filter to. In Figure 3 that follows, we use an example date range between 2024-07-03 and 2024-07-17.
- In the same Report Parameter area, under Filters, for Service, select SNS (Simple Notification Service). Because Amazon Cognito uses Amazon SNS for delivery of SMS messages, filtering on SNS can help you identify excessive billing.

Figure 3: Reviewing billing charges by service
Apply AWS WAF rules as mitigation approaches
It’s recommended that you apply AWS WAF with your Amazon Cognito user pool to protect against common threats. In this section, we show you a few advanced options using AWS WAF rules to block or throttle specific bad actor’s traffic when you have observed irregular sign-up attempts and suspect they were part of fraudulent activities.
Target a specific bad actor’s IP address
When building AWS WAF remediation strategies, you can start by building an IP deny list to block traffic from known malicious IP addresses. This method is straightforward and can be highly effective in preventing unwanted access. For detailed instructions on how to set up an IP deny list, see Creating an IP set.
Target a specific phone number area code regex pattern
In an SMS pumping scheme, bad actors often purchase blocks of cell phone numbers from a wireless service provider and use phone numbers with the same area code. If you observe a pattern and identify that these attempts use the same area code, you can apply an AWS WAF rule to block that specific traffic.
To configure an AWS WAF web ACL to block using an area code regex pattern:
- Open the AWS WAF console.
- In the navigation pane, under AWS WAF, choose WAF ACLs.
- Choose Create web ACL. Under Web ACL details, select Regional resources, and select the AWS Region as your Amazon Cognito user pool. Under Associated AWS resources, select Add AWS resources, and choose your Cognito user pool. Choose Next.
- On the Add rules and rule groups page, choose Add rules, Add my own rules and rule groups, and Rule builder.
- Create a rule in Rule builder.
- For If a request, select matches the statement.
- For Inspect, select Body.
- For Match type, select Matches regular expression.
- For Regular expression, enter a match for the observed pattern. For example, the regular expression
^303|^\+1303|^001303will match requests that include the digits 303, +1303, or 001303 at the beginning of any string in the body of a request:

Figure 4: Creating a web ACL
- Under Action, choose Block. Then, choose Add rule.
- Continue with Set rule priority and Configure metrics, then choose Create web ACL.

Be aware that this method will block all user sign-up requests that contain phone numbers matching the regex pattern for the target area code and could prevent legitimate users whose numbers match the defined pattern from signing up. For example, the rule above will apply to all users with phone numbers starting with 303, +1303, or 001303. You should consider implementing this method as an as-needed solution to address an ongoing SMS pumping attack.
Target a specific bad actor’s client fingerprint
Another method is to examine an actor’s TLS traffic. If your application UI is hosted using Amazon CloudFront or Application Load Balancer (ALB), you can build AWS WAF rules to match the client’s JA3 fingerprint. The JA3 fingerprint is a 32-character MD5 hash derived from the TLS three-way handshake when the client sends a ClientHello packet to the server. It serves as a unique identifier for the client’s TLS configuration because various attributes such as TLS version, cipher suites, and extensions are derived to calculate the fingerprint, allowing for the unique detection of clients even when the source IP and other commonly used identification information might have changed.
Fraudulent activities, such as SMS pumping, are typically carried out using automated tools and scripts. These tools often have a consistent SSL/TLS handshake pattern, resulting in a unique JA3 fingerprint. By configuring an AWS WAF web ACL rule to match the JA3 fingerprint associated with this traffic, you can identify clients with a high degree of accuracy, even if they change other attributes, such as IP addresses.
AWS WAF has introduced support for JA3 fingerprint matching, which you can use to identify and differentiate clients based on the way they initiate TLS connections, enabling you to inspect incoming requests for their JA3 fingerprints. You can build the remediation strategy by first evaluating AWS WAF logs to extract JA3 fingerprints for potential malicious hosts, then proceed with creating rules to block requests where the fingerprint matches the malicious JA3 fingerprint associated with previous attacks.
To configure an AWS WAF web ACL to block using JA3 fingerprint matching for CloudFront resources:
- Open the AWS WAF console.
- In the navigation pane, under AWS WAF, choose WAF ACLs.
- Choose Create web ACL. Under Web ACL details, select Amazon CloudFront distributions. Under Associated AWS resources, select Add AWS resources, and select your CloudFront distribution. Choose Next.
- On the Add rules and rule groups page, choose Add rules, Add my own rules and rule groups, and Rule builder.
- In Rule builder:
- For If a request, select matches the statement.
- For Inspect, select JA3 fingerprint.
- For Match type, keep Exactly matches string.
- For String to match, enter the JA3 fingerprint that you want to block.
- For Text transformation, choose None.
- For Fallback for missing JA3 fingerprint, select a fallback match status for cases where no JA3 fingerprint is detected. We recommend choosing No match to prevent unintended traffic blocking.
- If you need to block multiple JA3 fingerprints, include each one in the rule and for If a request select matches at least one of the statements (OR).

Figure 5: Creating an AWS WAF statement for a JA3 fingerprint
- Under Action, select Block, and choose Add rule. You can choose other actions such as COUNT or CAPTCHA that suit your use case.
- Continue with Set rule priority and Configure metrics, then choose Create web ACL.

Note that JA3 fingerprints can change over time due to the randomization of TLS ClientHello messages by modern browsers. It’s important to dynamically update your web ACL rules or manually review logs to update the JA3 fingerprint search string in your match rule when applicable.
AWS WAF remediation considerations
These AWS WAF remediation approaches help to block potential threats by providing mechanisms to filter out malicious traffic. It’s essential to continually review the effectiveness of these rules to minimize the risk of blocking legitimate sources and make dynamic adjustments to the rules when you detect new bad actors and patterns.
Summary
In this blog post, we introduced mechanisms that you can use to detect and protect your Amazon Cognito user pool against unintended user sign-up and SMS pumping. By implementing these strategies, you can enhance the security of your web and mobile applications and help to safeguard your services from potential abuse and financial loss. We suggest that you apply a combination of these prevention, detection, and mitigation approaches to protect your Cognito user pools.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Security updates for Friday
Post Syndicated from jzb original https://lwn.net/Articles/990202/
Security updates have been issued by Fedora (haproxy, osc, and python3.11), Oracle (389-ds:1.4), Red Hat (kernel), SUSE (clamav, colord, kernel, postgresql16, and qemu), and Ubuntu (linux, linux-aws, linux-aws-5.15, linux-gcp, linux-gcp-5.15, linux-gke, linux-gkeop, linux-gkeop-5.15, linux-hwe-5.15, linux-ibm, linux-intel-iotg, linux-intel-iotg-5.15, linux-kvm, linux-nvidia, linux-oracle, linux-raspi, linux-azure, linux-azure-5.15, linux-azure-fde, linux-lowlatency-hwe-6.8, linux-nvidia-6.8, and linux-xilinx-zynqmp).
The Growing Importance of Exposure Management: Our Key Insights from Gartner® Hype Cycle™ for Security Operations, 2024
Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/09/13/the-growing-importance-of-exposure-management-our-key-insights-from-gartner-r-hype-cycle-for-security-operations-2024/
The Gartner® Hype Cycle™ for Security Operations, 2024 was published in late July, and is an interesting look at the dynamic nature of both the threat landscape and the diverse range of technologies that security & risk management (SRM) professionals use to safeguard their organizations.
Understanding the Hype Cycle
Gartner Hype Cycles provide a graphic representation of the maturity and adoption of technologies and applications, and how they are potentially relevant to solving real business problems and exploiting new opportunities. Over 90 Hype Cycles are published per year. Hype Cycles provide a snapshot of the relative market penetration, maturity and benefit of innovations within a certain segment, such as a technology area or business market. This Hype Cycle helps security and risk management leaders strategize and deliver SecOps capability and functions.
What we think are key themes from this year’s Hype Cycle for SecOps
The 2024 Hype Cycle has seen some notable additions and consolidations, particularly around the rapidly-evolving Threat Exposure Management (TEM) market, as existing vulnerability assessment and management approaches mature to support the Continuous Threat Exposure Management (CTEM) framework. In the report Gartner defines CTEM as “a program helping organizations to improve their maturity when they govern and operationalize the five recommended phases of exposure management: scoping, discovery, prioritization, validation and mobilization.’”
Three new profiles reflect this evolution:
- Threat Exposure Management – This is intended to help organizations answer the question, “ow exposed are we?” It extends traditional approaches to vulnerability management to focus on risk reduction across a much wider potential attack surface, including cloud, SaaS applications and the third-party supply chain.
Today,many organizations currently have a siloed approach to exposure management across many different domains — external, vulnerability scanning, penetration testing — and are struggling to keep up with the pace of environmental change.
Gartner rates the potential benefit of Threat Exposure Management as ‘transformational’ and states that organizations should ‘employ proper governance and repeatability to make their threat exposure management programs continuous.’
- Exposure assessment platforms (EAPs) – This is a new category with a ‘high’ benefit rating from Gartner. In the report, Gartner states that EAPs ‘continuously identify and prioritize exposures, such as vulnerabilities and misconfigurations, across a broad range of asset classes. They natively deliver or integrate with discovery capabilities, such as assessment tools that enumerate exposures like vulnerabilities and configuration issues, to increase visibility.’
Gartner has removed both vulnerability assessment (VA) and vulnerability prioritization technologies (VPT) from this year’s Hype Cycle, stating that they have been ‘subsumed into exposure assessment platforms.’
We believe that a potential benefit of EAPs is to provide better insights into high-risk exposures, which could allow organizations to prevent security incidents and breaches. They can also improve operational efficiency by providing centralized visibility of assets and exposures, supporting risk scoring reporting and trend analysis across the organization.
Rapid7 is named as a Sample Vendor for EAP in this latest report.
- Adversarial exposure validation – The third new category related to exposure management covers the validation pillar of a CTEM program. As noted in the report, “Adversarial exposure validation technologies offer offensive security technologies simulating threat actor tactics, techniques, and procedures to validate the existence of exploitable exposures and test security control effectiveness. Within this profile, Gartner has consolidated breach attack simulation and autonomous penetration testing and red teaming. “
Gartner recommends that security and risk leaders should ‘Integrate existing attack simulation and penetration testing scenarios into an adversarial exposure validation roadmap, as part of a shift from vulnerability management to a CTEM program.’
As well as these new categories, we also see movement among some of the existing technologies that can support CTEM initiatives – notably Cyber Asset Attack Surface Management (CAASM), External Attack Surface Management (EASM) and Digital Risk Protection Services (DRPS).
Both EASM and DRPS are in the ‘Trough of Disillusionment’ on this year’s Hype Cycle. Gartner notes, “SRM leaders are reevaluating the value they’re getting from technologies in the trough, often having to reinforce their justification for budgets. For example:[…] Enterprises were unprepared to consume and operationalize service output (digital risk protection services, external attack surface management, ITDR).
CAASM has moved from ‘Innovation Trigger’ to the ‘Peak of Inflated Expectations’, reflecting the growing demand from enterprises to gain better visibility of their attack surfaces. CAASM helps provide more comprehensive visibility into assets by consolidating asset and exposure information into a holistic view. Noetic Cyber, a recent acquisition of Rapid7, is also a Sample Vendor for CAASM.
Rapid7’s vision for Exposure Management
Rapid7 recently announced the availability of Exposure Command and Surface Command, the first two solutions launched on the new Command Platform. Surface Command provides 360-degree visibility across the internal and external environment by bringing together EASM and CAASM in a single solution, enabling security teams to view and prioritize high-risk assets across their extended environments.
Building on the unparalleled visibility provided by Surface Command, Exposure Command expands traditional vulnerability management programs with insights and context from vulnerability, cloud and application security tools, establishing a single, consolidated platform for exposure management across the organization.
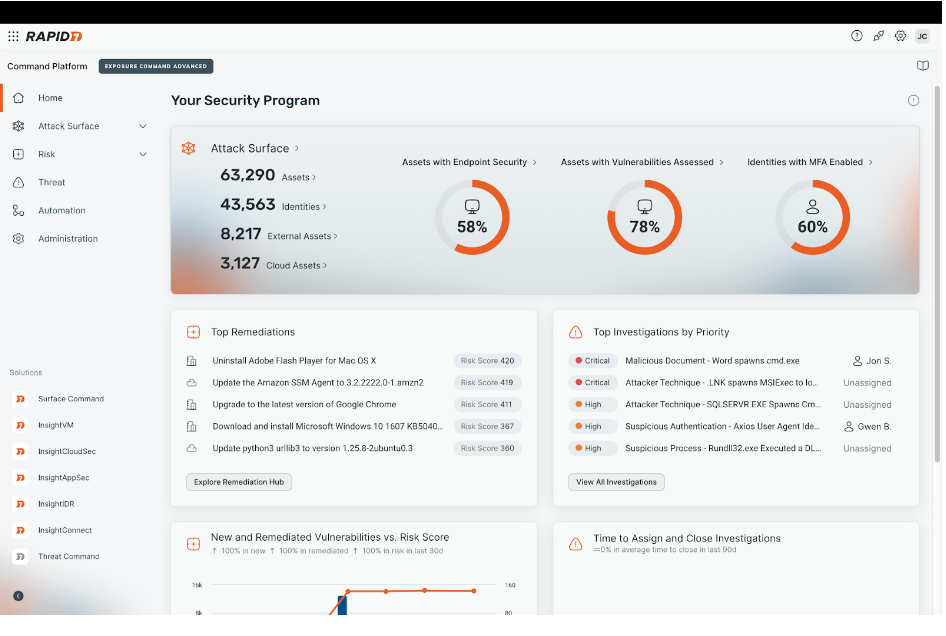
This centralized point of exposure management allows security leaders to prioritize based on the overall risk to the business, understand complex attack paths across the cloud and on-premise environments, and surface the top areas teams need to focus on and while elevating the mitigation activities that would have the largest impact in reducing the overall risk score of your environment.
We believe that these new capabilities align well with the Gartner concept of exposure assessment platforms and the overall requirements of a threat exposure management program. To understand more about Rapid7’s approach to attack surface and exposure management, you can find out more here.
Gartner, Hype Cycle for Security Operations, 2024, July 2024.
GARTNER is a registered trademark and service mark of Gartner, Inc. and/or its affiliates in the U.S. and internationally, and HYPE CYCLE is a registered trademark of Gartner, Inc. and/or its affiliates and are used herein with permission. All rights reserved.
Gartner does not endorse any vendor, product or service depicted in its research publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
Capture the Courts
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=Z13Je0PyeQc
3dfx Voodoo 3 3500 TV: Video, Radio, BIG DONGLE
Post Syndicated from LGR original https://www.youtube.com/watch?v=VDkhN-e42A8
Strange Deaths of Medieval Royalty
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=Cs0NcxwZwEo
Кои са най-важните проблеми за американците в изборната година? Част 2: Имиграция, здравеопазване, външна политика
Post Syndicated from Йоанна Елми original https://www.toest.bg/koi-sa-nay-vajnite-problemi-za-amerikantsite-v-izbornata-godina-chast-2/

Имигранти, които ядат кучета и котки. Ако преди два месеца, когато излезе първата част на този анализ, някой можеше да предскаже как ще започнем втората… вероятно щях да му повярвам, защото все пак е изборна година, а никой не прави по-добро изборно шоу от САЩ.
„В Спрингфийлд [Охайо – б.а.] ядат кучетата. Хората, които са дошли там, ядат котките. Ядат – ядат домашните любимци на хората, които живеят там“, заяви по време на вторите кандидатпрезидентски дебати бившият президент Доналд Тръмп. И това бързо се превърна в меме.
I better go superviral for this… pic.twitter.com/00Laf5QUrx
— Fearghas Kelly (@FearghasKelly) September 11, 2024
Изказванията на Тръмп, комбинирани с песен от анимацията „Семейство Симпсън“, които също живеят във въображаем Спрингфийлд
Майк Деуайн, републиканският губернатор на щата Охайо, заяви по време на пресконференция, че „имигрантите от Хаити, които са тук, ако говорите с представители на местната власт, ако питате хората, те също се справят добре. Ходят на работа. Някои от тях не говорят английски, имаме известни проблеми по отношение на здравеопазването, но много от тях полагат усилия да се осигурят и да получат достъп до здравни услуги“. Деуайн отчита, че са възможни проблеми, когато голям брой хора се преместят от друга държава, където здравеопазването е на много по-ниско ниво, но набляга на „възможността“ за възникване на такива проблеми. В рамките на обръщение към общността властите в Спрингфийлд заявиха, че не са открили никакви доказателства за вреди, нанесени на животни от страна на имигрантите. Слуховете са тръгнали от история отпреди месец, извън Спрингфийлд, с извършител, който вече е арестуван.
„Подобни слухове отвличат вниманието от реалните проблеми, като тези с липсата на жилища, ресурси в училищата и издъхващата здравна система“, каза кметът на града Роб Рю.
Страшните мигранти или добрата стара дезинформация?
Изказванията на местните власти не попречиха нито на Тръмп, нито на неговия кандидат за вицепрезидент Джей Ди Ванс да повторят опорката в ефир пред милиони. Ванс заяви, че градската управа няма как да знае за какво става въпрос, защото не е „на терен“, и че самият той е получил множество сигнали от избиратели за гъски, които са улавяни в езерата, за да бъдат колени, както и за изядени домашни любимци.
Въпреки изобилието от медийно отразяване на историята през последните дни Ванс обвини медиите, че не говорят за проблема. Тези твърдения той направи пред журналистката от CNN Кейтлан Колинс, която в отговор го попита: „Ако някой ви се обади и ви каже, че е видял Голямата стъпка, това не значи, че е видял Голямата стъпка. Имате отговорност като кандидат, както и бившият президент, да не разпространявате невярна информация, нали?“
“If someone calls your office and says they saw Bigfoot, that doesn’t mean they saw Bigfoot. You have a sense of responsibility as a running mate, and he certainly does as the candidate, to not promote false information, right?” pic.twitter.com/sUfbsgtMm8
— Kaitlan Collins (@kaitlancollins) September 11, 2024
Източникът на въпросната информация е обичайната изолирана екосистема от алт-райт и консервативно манипулирано съдържание. Разследване на Daily Dot разкрива първоизточника: ареста на Алекис Телия Ферел, живееща в град Кантън, Охайо, която „смачква главата на котката си и я изяжда пред очите на множество свидетели в жилищен квартал“ на 16 август. Ферел е регистрирана гласоподавателка в Охайо от шест години насам и няма никакви данни да е от Хаити.
Базираният в Малайзия коментатор Майлс Ченг разпространява полицейски записи от ареста сред своите милион последователи в X. „Наркотици?“ пита неизвестен потребител? „По-лошо. Хаитянци“, отговаря Ченг от своя виртуален „терен“. Напълно безпочвената информация се разпространява мълниеносно в социалната мрежа (откакто Х бе придобит от Илън Мъск, манипулативно съдържание от всякакъв вид циркулира почти безпрепятствено). „Тази да не е от Хаити? Те правят така тука“, пише друг анонимен потребител. „Чувам такива истории за кучета и котки, които ги ядат нелегалните.“ Подобни безпочвени твърдения се споделят от множество алтернативни и десни инфлуенсъри, като Чарли Кърк. Сред тях е и снимка на мигрант, държащ гъска, а фотографията всъщност е направена в град Калъмбъс, Охайо.
Въпреки че полицията в Спрингфийлд излезе с официална позиция, че не е получавала никакви сигнали за изчезнали животни, както и че в други форуми като Reddit потребители и местни не сигнализират за подобни случаи, невярната информация паразитира върху адаптирането на новодoшлите мигранти от Хаити – между 15 000 и 20 000 в град с население от 60 000 души.
Добре познати теми
Имиграцията е сред основните проблеми, които вълнуват американците. Колко зависи от това за кого гласуват и какви медии четат и гледат? Пресни данни от 9 септември 2024 г. поставят икономиката на първо място както за демократите, така и за републиканците. Оттук нататък обаче картината се променя. Ако имиграцията е на второ място за републиканците, следвана от престъпността и външната политика, то за демократите най-важните проблеми след икономиката са здравеопазването и назначенията във Върховния съд.
От януари насам „престъпленията на мигрантите“ са основна тема на коментаторските сегменти в консервативната Fox News. „Мигрантите престъпници убиват американците“, „Президентът Джо Байдън е инструмент за убийства“, „ВЪЛНА ОТ МИГРАНТИ ПРЕСТЪПНИЦИ ЗАЛИВА АМЕРИКА“ – това са стандартни заглавия в делнична вечер.
Обсебеността от мигрантите престъпници не е нещо ново. Tя е сред основните опорни точки на алтернативните медии в САЩ, както и на дясната Fox News, а още по време на първата си президентска кампания през 2016 г. Доналд Тръмп заяви, че „Мексико изпраща убийци и изнасилвачи“ в страната. Таблоиди като New York Post генерират съдържание, подобно на българските ПИК и БЛИЦ, залагайки на криминални хроники и сензационни заглавия с непропорционално отразяване на инциденти и престъпления, извършени от цветнокожи и имигранти. Множество експерти, от учени до журналисти, посочват, че крайнодясната медийна екосистема функционира като изолиран балон, в който събития се навързват в алтернативна реалност с помощта на манипулация и невярна информация.
Затова няма никакво значение, че според статистиката престъпленията срещу собствеността (кражби, палежи, обири) са много по-чести от престъпленията срещу личността (убийства, изнасилвания). Нито че честотата на престъпленията като цяло е спаднала драстично от 90-те години насам. Нито че за имигрантите е много по-малко вероятно да извършат престъпление в сравнение с родените в САЩ. Защото тук не става въпрос за факти и данни, а за история, стара като света: „те“ – различните, неудобните, цветнокожите – идват, пазете се. И ако през първите десетилетия от създаването на САЩ на мушка са били католиците, след това източноевропейците, после китайците и японците и т.н., то днес е ред на хаитяните.
Здравеопазването: идея за план
По време на дебата във вторник бившият президент Тръмп отново се закани да отмени и замени Закона за защита на пациентите и достъп до здравеопазване, познат като Obamacare. В рамките на изключително сложната система на здравеопазване в САЩ законът цели да предостави достъпно осигуряване на възможно най-много американци. За да се изговорят всички детайли, плюсове и минуси около него, няма да стигнат и два пълни материала. Но според независими експерти на този етап плюсовете са повече от минусите, поне за средностатистическите американци. Важно е също да се каже, че законът е обект на ежегодни промени и допълнения.
Попитан с какво ще замени закона, който дава на хиляди американци достъп до осигуряване, Тръмп отговори, че има идея за план. По време на първия си мандат бившият президент не успя нито да предложи конструктивни промени в законодателството, нито да го отмени въпреки няколкото си опита. В междинните избори през 2018 г. демократите поставиха здравеопазването в центъра на кампанията и така си върнаха контрола над Камарата на представителите. През 2019 г. Тръмп се закани, че ако спечели изборите, ще разкрие план, който „направо ще отвее Obamacare“. Преди да изгуби изборите през 2020 г., каза, че „след две седмици одобряваме план за здравеопазване, пълен и завършен план за здравно осигуряване“.
САЩ харчи около 18% от БВП за здравеопазване, но американците умират по-млади и боледуват повече от граждани на други страни със сходни доходи и стандарт на живот. Освен това САЩ е страната с най-висок процент на починали по предотвратими причини. Страната е единствената сред развитите, която няма изградена система за универсално здравно осигуряване.
В допълнение на тези черни статистики са най-ниска очаквана продължителност на живота при раждане в сравнение с повечето развити страни, най-голям дял хора с множество хронични заболявания, процент на затлъстяване двойно над средните стойности на ОИСР, най-висока смъртност при родилки и новородени отново в сравнителен план, както и значителна честота на самоубийствата. Дали предложенията на Камала Харис за подобряване на Obamacare ще подобрят тези стойности, няма как да знаем – мерките могат да се оценят само след като се приложат.
Независимо от партийната принадлежност американците подкрепят мерки, вече предложени от Харис, като замразяването на цените на инсулина. Това продължава опитите на администрацията на Джо Байдън за сваляне на цените на ключови животоспасяващи лекарства. Концепциите за план, от друга страна, си остават просто липса на решение за много сериозни проблеми.
Външна политика
Няколко часа след дебата Тръмп обяви, че според всички проучвания той е спечелил. Статистическите въпросници, които разчитат на представителна и методологически точна извадка, обаче сочат, че победителят е Харис. Данните, цитирани от Тръмп, са от въпросници онлайн, които позволяват на неограничен брой потребители да кликват и отговарят, независимо на каква възраст са и къде живеят. След дебата Харис води пред Тръмп с около 5%.
До ноември обаче има още много време поне ако го измерваме в предизборни дни. Двата външнополитически конфликта – в Палестина и руската инвазия в Украйна – нямат потенциал да решат изборите, но със сигурност могат да им повлияят, особено ако има ключово развитие в една или друга посока. Други важни елементи са външната политика спрямо Китай и бедственото изтегляне от Афганистан; тук можем да причислим и имиграцията, доколкото двустранните отношения със страните от Латинска Америка могат да влияят.
Политиката на Тръмп в тази област не се различава от първия му мандат: опасна игра с диктатори, славословене на авторитарни лидери като Виктор Орбан, изолационизъм и враждебност спрямо Китай и латиноамериканските имигранти – републиканският слон има какво да изпочупи в стъкларския магазин на света, много по-крехък, отколкото в периода 2016 – 2020 г. Тръмп се закани, че ще прекрати войната в Украйна, още преди да встъпи в длъжност. Но и тук, както в случая със здравеопазването, не са ясни конкретните мерки, които той смята да предприеме.
Харис напомни на гласоподавателите, че митата на Тръмп им струват скъпо – както финансово, така и по отношение на сигурността (администрацията на Байдън запази митата на Тръмп, а Харис също подкрепя определени мита като икономическа мярка). Предателство спрямо Украйна би означавало оттегляне от основни разбирания за суверенитет и териториална цялост, на които е изграден светът след Втората световна война. И това предателство може да има катастрофални последствия. В една от най-умелите си реплики Харис се обърна директно към огромната полска диаспора в щата Пенсилвания (където се намира Филаделфия, градът на провеждане на дебата): „Защо не кажеш на 800-те хиляди американци от полски произход тук, в Пенсилвания, колко бързо ще се предадеш в името на това да те покровителстват, и как, мислиш, би изглеждало едно приятелство с диктатор, който ще те изяде за закуска?“
Войната в Газа не беше основна тема по време на дебатите. Както и с Украйна, Тръмп се закани да реши конфликта бързо, без обаче да обясни как. Бившият президент избегна въпрос как би преговарял с премиера на Израел Бенямин Нетаняху и с „Хамас“, за да се стигне до прекратяване на огъня и на избиването на цивилни, както и до освобождаване на израелските заложници. Тръмп е отявлен поддръжник на Нетаняху. Камала Харис подчерта подкрепата на САЩ за Израел, но и каза, че създаването на независима палестинска държава (т.нар. двустранно решение) е надежден път към сигурност. Откритата ѝ заявка, че войната трябва да приключи, може да се интерпретира негативно в Израел.
Ден след дебата Тръмп заяви, че повече няма да участва в дебати, както и че дебатът е бил нагласен в полза на Харис, макар да го е спечелил според всички анкети и да се е справил добре. Какво друго всъщност остава да се каже? Дебатът приключи, но борбата тепърва предстои.
Големият взрив и корабът на Тезей
Post Syndicated from Емилия Милчева original https://www.toest.bg/golemiyat-vzriv-i-korabut-na-tezey/

Българската политика не е заразена от вируса на разцеплението, а от трансформация и макар процесът да започна от най-старите партии на статуквото БСП и ДПС, ще засегне всички политически сили – до една. Факторите за този рестарт се натрупваха: политическата криза, войната в Украйна, демографската криза и смяната на поколенията. Средата се променяше, променяха се и избирателите, но политиците на върха, вкопчени в своите тронове, изглеждаха непоклатими.
До днес.
Снимката
На пръв поглед изглежда като преконфигуриране на политическото пространство, но всъщност са процеси на разруха. Изхвърлянето на Корнелия Нинова като партиен лидер, така както самата тя изхвърли мнозина свои противници от партията, е само епизод от сериала „Носферату“ на „Позитано“ 20. БСП успя да се превърне в кавър на „Възраждане“, а съюзяването с бивши функционери, приети отново във VIP каютите на кораба майка, ще увеличи единствено битката за по-добрите места на горната палуба.
БСП има опит с вътрешнопартийните преврати. Така беше свален Тодор Живков, впоследствие Жан Виденов – след един денонощен инфарктен конгрес на БСП. А Корнелия Нинова направо беше изхвърлена от партията без шанс за завръщане, което потвърди и съдът. Дали това отваря път за коалиция с ГЕРБ, след като Нинова винаги е поддържала ролята на БСП като опозиция? Лидерът на ГЕРБ Бойко Борисов пръв обяви евентуална коалиция след 27 октомври.
Естествените партньори са тези, които бяхме в „сглобката“ [ГЕРБ, ПП–ДБ и ДПС – б.а.], плюс БСП и ИТН.
Временният председател на БСП Атанас Зафиров се измъкна от категоричен отговор – „ние в този пазарлък не участваме“, „имаме си колективни органи“ и т.н. Само преди три месеца беше казал, че БСП няма да участва в кабинет с ГЕРБ–СДС и ДПС „под никаква форма“.
Никой от ДПС-тата не коментира „естествените партньори“ – нито от фракцията на естествения партньор Пеевски, нито от „автентичното“ ДПС, скупчено около почетния председател Доган. Но вече е ясно как двете части ще се явят на избори – „ДПС – Ново начало“ (Пеевски) и „Алианс за права и свободи“ (Доган).
„Наблюдаваме агонията на динозаврите.“ Така социоложката Боряна Димитрова от „Алфа Рисърч“ определи по БНР случващото се в БСП и ДПС.
Това са единствените две партии, които присъстват в българския парламент от началото на Прехода. Сега наблюдаваме разпада на един модел, който специално за ДПС, а и в много моменти от историята на БСП беше антидемократичен и авторитарен, оплетен в доста икономически обвързаности.
Корабът
В класическия философски парадокс за кораба на Тезей се поставя въпросът дали един обект остава същият, ако всички негови части постепенно се заменят. Ще бъде ли пак същият кораб, ако оригиналните дъски до една бъдат подменени поетапно, докато той все още плава, пита Плутарх. Тоест парадоксът подсказва, че системата се самовзривява, когато промените в нейните части станат толкова значителни, че нарушат основната ѝ идентичност.
Най-старите системни партии – БСП и ДПС – се срутиха, защото отдавна са изгубили връзка със своята изначална мисия/кауза, в политическата история те ще бъдат запомнени като „майка“ и „баща“ на клептократичния модел, надграден от ГЕРБ. Лявото не е идентификация за БСП, нито либерализмът за ДПС, чиято авторитарна конструкция е несъвместима с въпросната политическа философия с основна цел свободата.
Социалният популизъм на БСП вече трудно прилъгва избиратели, освен носталгиците по социализма, а и те намаляват. Докато управляваше, партията следваше не принципите и целите на истинската лява политика, а на обогатяване на елита си и на олигархичните си структури. Този модел е до голяма степен наследен от БКП, управлявала еднопартийната система с авторитарен режим, обслужвайки комунистическата върхушка. Голямото неравенство в България, за което толкова много обичат да говорят политиците от „Позитано“ 20, е резултат от модела на Прехода, зададен от функционери на същата тази партия и от неолибералните политики, които прегърна. Тези „другари“ заедно с високопоставени служители на ДС имаха достъп до вътрешна информация, връзки и ресурси, които им позволиха да сключат съмнителни сделки, придобивайки държавни активи на много ниски цени.
Принос за този модел има и ДПС с ролята си на „балансьор“ между различните кланове и проводник на интересите на групировки, създадени от хора на бившите служби. И ако ДПС случи на избиратели, които не се разбягаха поради спойката на етноса, при БСП отливът беше на вълни и те се отдръпваха след всяко управление на т.нар. социалисти.
Първата беше след националната катастрофа 1996–1997 г., когато фалираха 16 банки, бюджетът претърпя осем актуализации за две години, а хиперинфлацията доведе до масово обедняване и икономически колапс. Следващата беше след Тройната коалиция, когато се роди ГЕРБ и БСП никога не се върна на власт освен с отделни министри. През този период БСП се превърна в националпопулистка и консервативна политическа сила, радикализира проруската си ориентация, а резултатът е, че разпадът ще продължи до пълното ѝ маргинализиране.
Такъв край очаква и ДПС, макар и не толкова бързо. Скоростта зависи от готовността на останалите политически сили да преодолеят предубежденията си за представители в листите на други етноси, различни от българския. Докато този вот остава сравнително монолитен, той ще гарантира политическо представителство за клановете, които ДПС представлява, не за избирателите, които нямат илюзии за порциите, раздавани на техен гръб. Но всесилното и мълчаливо ДПС, което познаваме, приключи.
Капанът на тази амбивалентност, каквато представляват интересите на управляващите кланове и партийната идеология, щракна и за БСП, и за ДПС. Партии, управлявани от милионери, които биват избирани от бедняци.
Първите преяли с власт се пръснаха.
Последствията
Разрухата в двете системни партии ще прекрои възможните коалиции. Отношението към ДПС 1 и ДПС 2 има потенциала да се превърне в червена линия за политическите сили. Ако и двете фракции на ДПС получат парламентарно представителство – напълно възможно при ниска избирателна активност, – всяка от тях би участвала в различни управленски сдружения. Например ИТН може да се комбинира с „Ново начало“, но не и с „Алианс за права и свободи“, а БСП и широката ѝ коалиция вероятно биха избрали „автентичността“. ПП–ДБ декларират неколкократно, че ще разграждат модела „Пеевски“, макар да бяха го привлекли като партньор в конституционно (и не само) мнозинство.
Кого ще предпочете ГЕРБ, чиито политици са така предпазливи (както и всички останали впрочем) за конфликта в Движението за права и свободи? Несъмнено Борисов ще изчака, макар че развръзката едва ли ще настъпи с изборите, а с предстоящия избор на главен прокурор, който Висшият съдебен съвет възнамерява да направи на 16 януари. Не е имало избор на главен прокурор, чието име да не е известно най-напред в един тесен политически кръг. Изборът на Никола Филчев е бил „мотивиран“ от председателя на 38-мия парламент Йордан Соколов, което потвърждава преди години по bTV председателката на Съюза на съдиите Нели Куцкова.
За избора на настоящия [към 2006 г. – б.р.] главен прокурор Никола Филчев имаше политически натиск върху някои от членовете на Висшия съдебен съвет.
Следващият главен прокурор Борис Велчев се издигна на поста, след като бе съветник на президента Георги Първанов. За Сотир Цацаров паметна ще остане фразата на един бивш вече градски прокурор към Бойко Борисов: „Не ми се подсмихвай, ти си го избра!“ Иван Гешев, някога наблюдаващ прокурор на делото КТБ, се издигна до главен, след като така и не разпозна Пеевски в документите за фалита на четвъртата по големина банка в България.
Разпадът в ДПС и БСП прави непредсказуеми резултатите от изборите на членове на ВСС от парламентарната квота, за да може нов ВСС да определи следващия главен прокурор. В края на юли Народното събрание удължи на 6 месеца срока, в който парламентът и органите на съдебната власт започват процедура за нов избор на членове на ВСС. Този срок изтича в края на януари. А според хронограмата на кадровиците на съдебната власт окончателният избор на нов главен прокурор трябва да е на 16 януари. Юристи отчитат, че шансовете да бъде спряна процедурата са нищожни.
Бързат клановете, бърза Борисов, бърза Пеевски. Колко му е в мътната вода на блатото да се улови един нов филчеввелчевцацаровгешев.
Скоро нищо няма да е същото. Идва времето и на ГЕРБ.
По буквите: Георги Господинов
Post Syndicated from Зорница Христова original https://www.toest.bg/po-bukvite-georgi-gospodinov/
„Градинарят и смъртта“ от Георги Господинов

Пловдив: изд. „Жанет 45“, 2024
Имам една любима картина на финския художник Хуго Симберг – „Градината на Смъртта“. В нея Смъртта кротко полива подредени върху висока леха крехки растения. Самата Смърт също е крехка, вглъбена, грижовна. Не знаем дали е мъж, или жена – бял скелет с черна пелерина, тъмнозелена лейка, едната ръка опряна на лехата, зад която се подава тънка бяла пета. В съседство виси бяла кърпа. На заден план – още лехи, още смърти. И все тъй нежни.
Свикнали сме да мислим, че градината е обратното на смъртта. Да градинарстваш значи да заставаш на страната на живота – през август хортензиите ми издържат само ден, ако не ги полея. Разбира се, природата няма много нужда от подобно съучастничество; тя прекрасно се справя и без нас. Градинарят обаче се грижи за конкретния живот, не за живота като цяло. Пази го от суша и от врагове, пресажда го, помага му да се прероди.
„Градинарят и смъртта“ е такава книга. Така се случи, че познавам много книги за смъртта – някои прекалено отблизо. „Годината на магическото мислене“ на Джоун Дидиън я преведох; тя описва в детайли какво чувства човек през първата година след опустошителна загуба. Такъв е и „Дневник на скръбта“ на Ролан Барт. И двете са болезнено точни; могат да ви накарат да бъдете мили с близките си, ако са още живи, и да се стреснете от образа си в огледалото, ако не са. Или да усетите несподелимото като все пак споделено.
Това, което изцяло отсъства и от двете книги, е образът на човека, който си е отишъл. Този образ присъства като отпечатък, разранен отпечатък. Други книги – всички биографии, да речем – се опитват да направят обратното: да възстановят отделния живот като разказ, в който смъртта е само (макар и финален) епизод.
„Градинарят и смъртта“ на Георги Господинов не е нито биография, нито дневник на скръбта – и все пак някак е и двете. Тя е мрежа за улавяне на живота, конкретния живот, който ни се изплъзва. Мрежа от истории. В романа „В памет на паметта“ Мария Степанова говори за една особена привилегия, срещу която никой още не се е сетил да се бори – привилегията на онези, чийто живот е интересен, онези, които запомняме. И това е дарът, който писателят може да направи за своите близки – да ги запази в истории, защото паметта е устроена като литературата.
„Градинарят и смъртта“ е портрет, който се състои от истории – подредени в привидно безредната, асоциативна вселена на паметта. Истории за бащата и истории за отпечатъка, за раната от неговото отсъствие.
Тук книгата се родее със сборника „Бащите не си отиват“ на издателство ICU, и с книги като „Наивно изкуство“ на Марин Бодаков. Включва се в улавянето на бащиния образ чрез истории на сборника, подхваща теми, които звучат в стихосбирката –
Каква супа е обичал баща ми като дете, дояждал ли си е чинията, какво е криел под голямата възглавница, на коя дума от приказките е заспивал, наистина ли се е плашил от бомбардировките, никога няма да науча това, моето отечество е безвъзвратно загубено.
Бих казала, че за първи път у нас едно поколение писатели (и не само) осмисля на глас смъртта и загубата – и отваря пространство за разговор към другите. „Градинарят и смъртта“ е част от този опит за братство пред бездната. И това е сила, не недостатък на книгата.
Кога, ако не в осиротяването на света, имаме нужда от общност, от действителния смисъл на „аз сме“?
Именно общото е и начинът да избегнеш дилемата при всяко говорене за мъртвите. Обичта те заставя да кажеш „или добро, или нищо“ – но паметта не понася плоски образи, едностранчиви герои, семейни светци. Без сянка образът се изтрива – или по-лошо, бива подменен и този, когото уж сме издърпали от подземното царство, се оказва някой друг, благообразно усмихнат… двойник. „Градинарят и смъртта“ решава тази дилема, като разказва за сянката – но я скрива в полето от сенки, в поколенческото, в общото. Бащите ни пускаха шамарената фабрика, казва книгата. Или „бащите ни отсъстваха“.
Книгата черпи от утехата на общото – но и умее да я дава, милостива е към читателя, който търси изречения за пластир върху раната. Някои са прастари коренища, за които човечеството се лови от векове, като ботаническото безсмъртие и Сенека. Други са нови. В трети се усещат – и предават – терапевтични модели. По-важното е, че споделяйки, книгата разширява отвореното от други книги пространство за споделяне, пуска в себе си читателя да разкаже и своята история, историята на своята мъка и на своите мъртви. И да каже наум – като автора в една среща от книгата – „и аз“.
Активните дарители на „Тоест“ получават постоянна отстъпка в размер на 20% от коричната цена на всички заглавия от каталозите на „Жанет 45“, „Лист“, ICU и няколко други български издателства в рамките на партньорската програма Читателски клуб „Тоест“. За повече информация прочетете на toest.bg/club.
В емблематичната си колонка, започната още през 2008 г. във в-к „Култура“, Марин Бодаков ни представяше нови литературни заглавия и питаше с какво точно тези книги ни променят. Вярваме, че е важно тази рубрика да продължи. От човек до човек, с нова книга в ръка.
Docker Raises Prices Up to 80 Percent and More
Post Syndicated from Cliff Robinson original https://www.servethehome.com/docker-raises-prices-up-to-80-percent-and-more/
Docker Pro annual pricing is increaseing by 80 percent while some of the benefits are being adjusted to the subscription level
The post Docker Raises Prices Up to 80 Percent and More appeared first on ServeTheHome.
Craters
Post Syndicated from xkcd.com original https://xkcd.com/2985/
The Demise of Long Henry
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=0npyrE6qBmE
Amazon RDS for MySQL zero-ETL integration with Amazon Redshift, now generally available, enables near real-time analytics
Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/amazon-rds-for-mysql-zero-etl-integration-with-amazon-redshift-now-generally-available-enables-near-real-time-analytics/
Zero-ETL integrations help unify your data across applications and data sources for holistic insights and breaking data silos. They provide a fully managed, no-code, near real-time solution for making petabytes of transactional data available in Amazon Redshift within seconds of data being written into Amazon Relational Database Service (Amazon RDS) for MySQL. This eliminates the need to create your own ETL jobs simplifying data ingestion, reducing your operational overhead and potentially lowering your overall data processing costs. Last year, we announced the general availability of zero-ETL integration with Amazon Redshift for Amazon Aurora MySQL-Compatible Edition as well as the availability in preview of Aurora PostgreSQL-Compatible Edition, Amazon DynamoDB, and RDS for MySQL.
I am happy to announce that Amazon RDS for MySQL zero-ETL with Amazon Redshift is now generally available. This release also includes new features such as data filtering, support for multiple integrations, and the ability to configure zero-ETL integrations in your AWS CloudFormation template.
In this post, I’ll show how you can get started with data filtering and consolidating your data across multiple databases and data warehouses. For a step-by-step walkthrough on how to set up zero-ETL integrations, see this blog post for a description of how to set one up for Aurora MySQL-Compatible, which offers a very similar experience.
Data filtering
Most companies, no matter the size, can benefit from adding filtering to their ETL jobs. A typical use case is to reduce data processing and storage costs by selecting only the subset of data needed to replicate from their production databases. Another is to exclude personally identifiable information (PII) from a report’s dataset. For example, a business in healthcare might want to exclude sensitive patient information when replicating data to build aggregate reports analyzing recent patient cases. Similarly, an e-commerce store may want to make customer spending patterns available to their marketing department, but exclude any identifying information. Conversely, there are certain cases when you might not want to use filtering, such as when making data available to fraud detection teams that need all the data in near real time to make inferences. These are just a few examples, so I encourage you to experiment and discover different use cases that might apply to your organization.
There are two ways to enable filtering in your zero-ETL integrations: when you first create the integration or by modifying an existing integration. Either way, you will find this option on the “Source” step of the zero-ETL creation wizard.

You apply filters by entering filter expressions that can be used to either include or exclude databases or tables from the dataset in the format of database*.table*. You can add multiple expressions and they will be evaluated in order from left to right.
If you’re modifying an existing integration, the new filtering rules will apply from that point in time on after you confirm your changes and Amazon Redshift will drop tables that are no longer part of the filter.
If you want to dive deeper, I recommend you read this blog post, which goes in depth into how you can set up data filters for Amazon Aurora zero-ETL integrations since the steps and concepts are very similar.
Create multiple zero-ETL integrations from a single database
You are now also able to configure up integrations from a single RDS for MySQL database to up to 5 Amazon Redshift data warehouses. The only requirement is that you must wait for the first integration to finish setting up successfully before adding others.
This allows you to share transactional data with different teams while providing them ownership over their own data warehouses for their specific use cases. For example, you can also use this in conjunction with data filtering to fan out different sets of data to development, staging, and production Amazon Redshift clusters from the same Amazon RDS production database.
Another interesting scenario where this could be really useful is consolidation of Amazon Redshift clusters by using zero-ETL to replicate to different warehouses. You could also use Amazon Redshift materialized views to explore your data, power your Amazon Quicksight dashboards, share data, train jobs in Amazon SageMaker, and more.
Conclusion
RDS for MySQL zero-ETL integrations with Amazon Redshift allows you to replicate data for near real-time analytics without needing to build and manage complex data pipelines. It is generally available today with the ability to add filter expressions to include or exclude databases and tables from the replicated data sets. You can now also set up multiple integrations from the same source RDS for MySQL database to different Amazon Redshift warehouses or create integrations from different sources to consolidate data into one data warehouse.
This zero-ETL integration is available for RDS for MySQL versions 8.0.32 and later, Amazon Redshift Serverless, and Amazon Redshift RA3 instance types in supported AWS Regions.
In addition to using the AWS Management Console, you can also set up a zero-ETL integration via the AWS Command Line Interface (AWS CLI) and by using an AWS SDK such as boto3, the official AWS SDK for Python.
See the documentation to learn more about working with zero-ETL integrations.
VirtualBox 7.1.0 released
Post Syndicated from jzb original https://lwn.net/Articles/990125/
Version
7.1.0 of the VirtualBox virtualization system has been
released. Changes include a major GUI update, a new Network Address
Translation (NAT) engine with IPv6 support, shared clipboard support on Wayland, and more.
Harness Zero Copy data sharing from Salesforce Data Cloud to Amazon Redshift for Unified Analytics – Part 2
Post Syndicated from Rajkumar Irudayaraj original https://aws.amazon.com/blogs/big-data/harness-zero-copy-data-sharing-from-salesforce-data-cloud-to-amazon-redshift-for-unified-analytics-part-2/
In the era of digital transformation and data-driven decision making, organizations must rapidly harness insights from their data to deliver exceptional customer experiences and gain competitive advantage. Salesforce and Amazon have collaborated to help customers unlock value from unified data and accelerate time to insights with bidirectional Zero Copy data sharing between Salesforce Data Cloud and Amazon Redshift.
In the Part 1 of this series, we discussed how to configure data sharing between Salesforce Data Cloud and customers’ AWS accounts in the same AWS Region. In this post, we discuss the architecture and implementation details of cross-Region data sharing between Salesforce Data Cloud and customers’ AWS accounts.
Solution overview
Salesforce Data Cloud provides a point-and-click experience to share data with a customer’s AWS account. On the AWS Lake Formation console, you can accept the datashare, create the resource link, mount Salesforce Data Cloud objects as data catalog views, and grant permissions to query the live and unified data in Amazon Redshift. Cross-Region data sharing between Salesforce Data Cloud and a customer’s AWS accounts is supported for two deployment scenarios: Amazon Redshift Serverless and Redshift provisioned clusters (RA3).
Cross-Region data sharing with Redshift Serverless
The following architecture diagram depicts the steps for setting up a cross-Region datashare between a Data Cloud instance in US-WEST-2 with Redshift Serverless in US-EAST-1.

Cross-Region data sharing set up consists of the following steps:
- The Data Cloud admin identifies the objects to be shared and creates a Data Share in the data cloud provisioned in the
US-WEST-2 - The Data Cloud admin links the Data Share with the Amazon Redshift Data Share target. This creates an AWS Glue Data Catalog view and a cross-account Lake Formation resource share using the AWS Resource Access Manager (RAM) with the customer’s AWS account in
US-WEST-2. - The customer’s Lake Formation admin accepts the datashare invitation in
US-WEST-2from the Lake Formation console and grants default (select and describe) permissions to an AWS Identity and Access Management (IAM) principal. - The Lake Formation admin switches to
US-EAST-1and creates a resource link pointing to the shared database in theUS-WEST-2Region. - The IAM principal can log in to the Amazon Redshift query editor in
US-EAST-1and creates an external schema referencing the datashare resource link. The data can be queried through these external tables.
Cross-Region data sharing with a Redshift provisioned cluster
Cross-Region data sharing across Salesforce Data Cloud and a Redshift provisioned cluster requires additional steps on top of the Serverless set up. Based on the Amazon Redshift Spectrum considerations, the provisioned cluster and the Amazon Simple Storage Service (Amazon S3) bucket must be in the same Region for Redshift external tables. The following architecture depicts a design pattern and steps to share data with Redshift provisioned clusters.

Steps 1–5 in the set up remain the same across Redshift Serverless and provisioned cluster cross-Region sharing. Encryption must be enabled on both Redshift Serverless and the provisioned cluster. Listed below are the additional steps:
- Create a table from datashare data with the
CREATE TABLE AS SELECTCreate a datashare in Redshift serverless and grant access to the Redshift provisioned cluster. - Create a database in the Redshift provisioned cluster and grant access to the target IAM principals. The datashare is ready for query.
The new table needs to be refreshed periodically to get the latest data from the shared Data Cloud objects with this solution.
Considerations when using data sharing in Amazon Redshift
For a comprehensive list of considerations and limitations of data sharing, refer to Considerations when using data sharing in Amazon Redshift. Some of the important ones for Zero Copy data sharing includes:
- Data sharing is supported for all provisioned RA3 instance types (ra3.16xlarge, ra3.4xlarge, and ra3.xlplus) and Redshift Serverless. It isn’t supported for clusters with DC and DS node types.
- For cross-account and cross-Region data sharing, both the producer and consumer clusters and serverless namespaces must be encrypted. However, they don’t need to share the same encryption key.
- Data Catalog multi-engine views are generally available in commercial Regions where Lake Formation, the Data Catalog, Amazon Redshift, and Amazon Athena are available.
- Cross-Region sharing is available in all LakeFormation supported regions.
Prerequisites
The prerequisites remain the same across same-Region and cross-Region data sharing, which are required before proceeding with the setup.
Configure cross-Region data sharing
The steps to create a datashare, create a datashare target, link the datashare target to the datashare, and accept the datashare in Lake Formation remain the same across same-Region and cross-Region data sharing. Refer to Part 1 of this series to complete the setup.
Cross-Region data sharing with Redshift Serverless
If you’re using Redshift Serverless, complete the following steps:
- On the Lake Formation console, choose Databases in the navigation pane.
- Choose Create database.
- Under Database details¸ select Resource link.
- For Resource link name, enter a name for the resource link.
- For Shared database’s region, choose the Data Catalog view source Region.
- The Shared database and Shared database’s owner ID fields are populated manually from the database metadata.
- Choose Create to complete the setup.


The resource link appears on the Databases page on the Lake Formation console, as shown in the following screenshot.

- Launch Redshift Query Editor v2 for the Redshift Serverless workspace The cross-region data share tables are auto-mounted and appear under
awsdatacatalog. To query, run the following command and create an external schema. Specify the resource link as the Data Catalog database, the Redshift Serverless Region, and the AWS account ID. - Refresh the schemas to view the external schema created in the
devdatabase

- Run the
show tablescommand to check the shared objects under the external database: - Query the datashare as shown in the following screenshot.


Cross-Region data sharing with Redshift provisioned cluster
This section is a continuation of the previous section with additional steps needed for data sharing to work when the consumer is a provisioned Redshift cluster. Refer to Sharing data in Amazon Redshift and Sharing datashares for a deeper understanding of concepts and the implementation steps.
- Create a new schema and table in the Redshift Serverless in the consumer Region:

- Get the namespace for the Redshift Serverless (producer) and Redshift provisioned cluster (consumer) by running the following query in each cluster:


- Create a datashare in the Redshift Serverless (producer) and grant usage to the Redshift provisioned cluster (consumer). Set the datashare, schema, and table names to the appropriate values, and set the namespace to the consumer namespace.
- Log in as a superuser in the Redshift provisioned cluster, create a database from the datashare, and grant permissions. Refer to managing permissions for Amazon Redshift datashare for detailed guidance.


The datashare is now ready for query.

You can periodically refresh the table you created to get the latest data from the data cloud based on your business requirement.
Conclusion
Zero Copy data sharing between Salesforce Data Cloud and Amazon Redshift represents a significant advancement in how organizations can use their customer 360 data. By eliminating the need for data movement, this approach offers real-time insights, reduced costs, and enhanced security. As businesses continue to prioritize data-driven decision-making, Zero Copy data sharing will play a crucial role in unlocking the full potential of customer data across platforms.
This integration empowers organizations to break down data silos, accelerate analytics, and drive more agile customer-centric strategies. To learn more, refer to the following resources:
- Sharing data in Amazon Redshift
- Sharing datashares
- Data sharing in AWS Lake Formation
- Building AWS Glue Data Catalog views
- Lake Formation supported regions
- Transform Your Data Strategy with the Power of Salesforce Data Cloud’s Zero Copy Integration to Amazon Redshift
About the Authors
 Rajkumar Irudayaraj is a Senior Product Director at Salesforce with over 20 years of experience in data platforms and services, with a passion for delivering data-powered experiences to customers.
 Sriram Sethuraman is a Senior Manager in Salesforce Data Cloud product management. He has been building products for over 9 years using big data technologies. In his current role at Salesforce, Sriram works on Zero Copy integration with major data lake partners and helps customers deliver value with their data strategies.
 Jason Berkowitz is a Senior Product Manager with AWS Lake Formation. He comes from a background in machine learning and data lake architectures. He helps customers become data-driven.
 Ravi Bhattiprolu is a Senior Partner Solutions Architect at AWS. Ravi works with strategic ISV partners, Salesforce and Tableau, to deliver innovative and well-architected products and solutions that help joint customers achieve their business and technical objectives.
 Avijit Goswami is a Principal Solutions Architect at AWS specialized in data and analytics. He supports AWS strategic customers in building high-performing, secure, and scalable data lake solutions on AWS using AWS managed services and open source solutions. Outside of his work, Avijit likes to travel, hike, watch sports, and listen to music.
 Ife Stewart is a Principal Solutions Architect in the Strategic ISV segment at AWS. She has been engaged with Salesforce Data Cloud over the last 2 years to help build integrated customer experiences across Salesforce and AWS. Ife has over 10 years of experience in technology. She is an advocate for diversity and inclusion in the technology field.
 Michael Chess is a Technical Product Manager at AWS Lake Formation. He focuses on improving data permissions across the data lake. He is passionate about enabling customers to build and optimize their data lakes to meet stringent security requirements.
 Mike Patterson is a Senior Customer Solutions Manager in the Strategic ISV segment at AWS. He has partnered with Salesforce Data Cloud to align business objectives with innovative AWS solutions to achieve impactful customer experiences. In his spare time, he enjoys spending time with his family, sports, and outdoor activities.