Part of running LWN is keeping a list of potentially interesting topics
that may merit the effort to turn into articles. As an experiment, we are now exposing that list to our subscribers at the
Project Leader and Supporter levels. The hope is that this list will
provide useful insights into what is on our radar and which might be coming
to LWN in the near future.
With this feature, we hope to give our most committed subscribers a look
behind the curtain and the ability to provide input on the topics they are
most interested in reading about. There, is, thus, a simple voting
mechanism built into this list. No topic will be chosen (or rejected)
solely on the basis of votes; there are a lot of considerations that go
into topic selection, and that will not change. But more information about
where our readers’ interests lie will, hopefully, be helpful.
For all readers: we are always happy to welcome topic suggestions sent to [email protected].
Amazon Redshift is a fully managed, AI-powered cloud data warehouse used by tens of thousands of customers to analyze exabytes of data with industry-leading price-performance. Amazon Redshift delivers SQL analytics across your entire lakehouse in Amazon SageMaker Unified Studio, unifying data from multiple sources. Zero-ETL integrations remove complex pipelines by connecting streaming, databases, and enterprise applications for near real-time insights.
On May 12, 2026, Amazon Redshift launched Graviton-based RG instances, a new generation of provisioned nodes. RG instances deliver up to 2.2x as fast for data warehouse workloads and up to 2.4x as fast for data lake workloads, at 30 percent lower price per vCPU compared to RA3 instances. RG instances support all data lake formats supported by RA3 and remove the per-TB scanning charges for Amazon Redshift Spectrum.
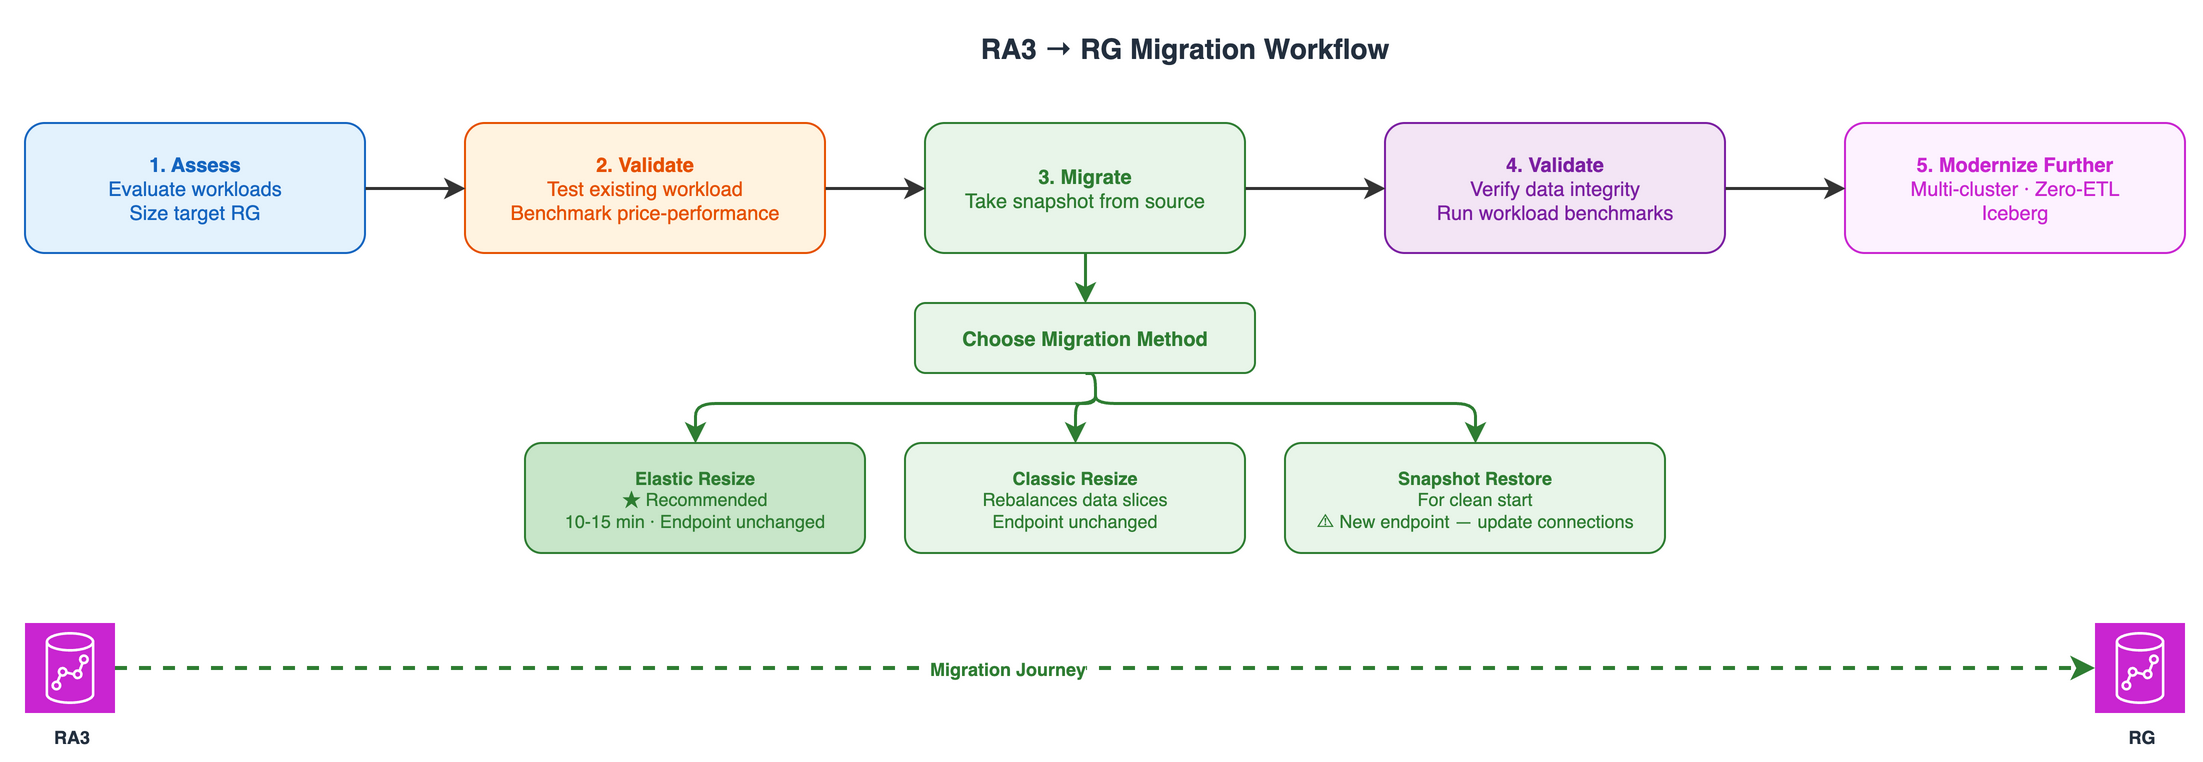
In this post, you learn how to migrate Amazon Redshift RA3 clusters to Graviton-based RG instances. We compare the Elastic Resize, Classic Resize, and Snapshot/Restore migration strategies, with key considerations and best practices to support a smooth migration. We also provide mapping guidance from RA3 to RG to help you right-size your cluster.
Who should migrate to RG?
We recommend that all RA3 customers plan their migration to RG to maximize price-performance. RG is designed to deliver improved performance for both compute-intensive and I/O-intensive workloads compared to RA3, so regardless of your workload pattern, you might see performance improvements. Amazon Redshift Graviton RG instances maintain feature parity with prior-generation RA3 instances, so you can migrate without loss of functionality.
RG node types
The RG instance family currently has two node types available. The following table shows the RG instance types, hardware specifications, and the equivalent RA3 node types. Use these specifications to inform sizing decisions when migrating from RA3.
Node type
Configuration
vCPU
Memory
Max storage/node
Node range
Status
RA3 equivalent
RG.xlarge
Multi Node
4
32 GB
16 TB
2-32
GA (05/12/2026)
Direct equivalent to RA3.xlplus.
RG.4xlarge
Multi Node Only
16
128 GB
128 TB
2-64
GA (05/12/2026)
1.33x more vCPUs and memory vs RA3.4xlarge
Note: We plan to extend support for additional instance types in the future to provide an optimal price/performance fit for your Amazon Redshift workloads.
3 RG nodes per 4 RA3.4xl nodes (round up to nearest even)
Note: These are starting recommendations. Depending on your specific workloads, you might need to adjust the target RG node configurations. We recommend testing your workload in a lower environment and validating performance before committing to a target configuration. To test a full production workload, you can also use the Amazon Redshift Test Drive utility.
Mapping consideration: Within the RG family, 1 node of RG.4xlarge equals 4 nodes of RG.xlarge.
Choosing between RG node types: When sizing your Amazon Redshift cluster, a key decision is whether to use fewer large nodes or a greater number of smaller nodes. The key differentiator between RG node types is local SSD cache capacity. Larger nodes provide more local cache per node, which reduces the need to fetch data from managed storage and improves performance for I/O-intensive queries.
Consider larger node types when your workload involves:
Significant disk spill – complex queries with large intermediate result sets that exceed available memory.
Leader node-heavy processing – high numbers of concurrent client connections, complex query compilation with many joins and subqueries, or heavy final-stage aggregation.
Large volumes of frequently accessed data – hot datasets that benefit from local SSD cache to minimize fetches from managed storage.
Large result sets – queries returning substantial data volumes back to the client application.
Frequent metadata operations – workloads with high catalog lookup activity or CURSOR-based fetches with many small batches.
Prerequisites
You must have the following prerequisites to follow along with this post.
An existing Amazon Redshift cluster running RA3 node types.
Elastic Resize is the recommended method for performing the node upgrade when the target RG node configuration falls within the supported bounds of Elastic Resize. You can use it to change the node type (for example, from RA3 to RG) and to add or remove nodes from an Amazon Redshift cluster.
When an Elastic Resize is performed, Amazon Redshift first creates a snapshot of the source cluster. A new target cluster is provisioned with the latest data from the snapshot, and data is transferred to the new cluster in the background. During this period, data is read-only. When the resize nears completion, Amazon Redshift updates the endpoint to point to the new cluster and drops all connections to the source cluster. Although unlikely, in case of a failure, rollback happens automatically in most cases without manual intervention.
Advantages
Typically completes quickly, taking approximately 10–15 minutes on average. We recommend it as your first option.
Minimal downtime, because the cluster remains in a read-only state during the resize operation.
Cluster endpoint remains the same, so no connection string changes are required.
Can be run on demand or scheduled during a maintenance window.
Considerations
When performing an Elastic Resize to change the node type on a producer cluster, data sharing is unavailable while connections are dropped and transferred to the new target cluster.
Verify that your target node configuration has enough storage for your existing data.
Not all target configurations are available under Elastic Resize. Consider Classic Resize or Snapshot/Restore in those cases.
An Elastic Resize operation can’t be canceled after it’s initiated.
Data slices remain unchanged. This can potentially cause some data or CPU skew.
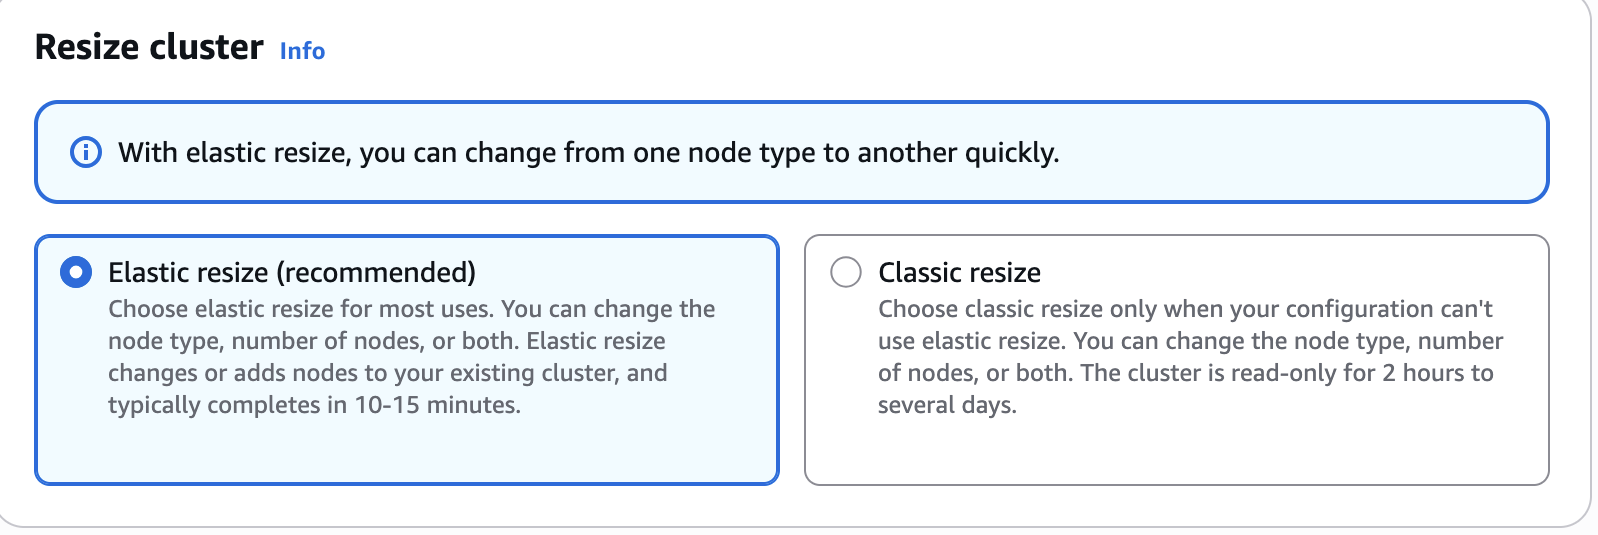
You can use either the AWS Management Console or the AWS CLI to initiate an Elastic Resize.
To resize a cluster using the console, follow these steps
Classic Resize is recommended when the change in cluster size or node type isn’t supported by Elastic Resize. It’s also required for single-node to multi-node conversions.
When you perform a Classic Resize, Amazon Redshift creates a target cluster and migrates your data and metadata from the source cluster using a backup and restore operation. This makes sure that all data, including database schemas and user configurations, is accurately transferred. The source cluster restarts initially and is unavailable for a few minutes. After that, the cluster becomes available for read and write operations while the resize continues in the background.
Enhanced Classic Resize comprises two stages:
Stage 1 (critical path): Migrating the metadata from the source cluster to the target cluster. During this stage, the source cluster is in read-only mode. This is typically a very short duration. The cluster is then made available for read and write queries. All tables with KEY distribution style are temporarily stored with EVEN distribution and are redistributed to KEY style in Stage 2.
Stage 2 (off critical path): Redistributing the data per the previous distribution style. This runs in the background. Duration depends on data volume, cluster workload, and node type.
Allows for comprehensive reconfiguration of the source cluster.
Rebalances data slices to the default per node, which leads to even data distribution across nodes.
Considerations
The size of the data on the source cluster must be below 2 petabytes (PB). Use the Snapshot/Restore approach for data larger than 2 PB.
Before initiating, make sure a manual snapshot is available that is no more than 10 hours old. If not, take a new manual snapshot.
The snapshot used to perform the Classic Resize can’t be used for a table restore or other purpose.
The cluster must be in a virtual private cloud (VPC).
While the resize is in progress, queries can take longer to complete. Consider enabling concurrency scaling.
Drop tables that aren’t needed before performing a Classic Resize to accelerate data distribution.
Classic Resize takes more time to complete than Elastic Resize.
Plan and schedule the resize operation during off-peak hours or maintenance windows.
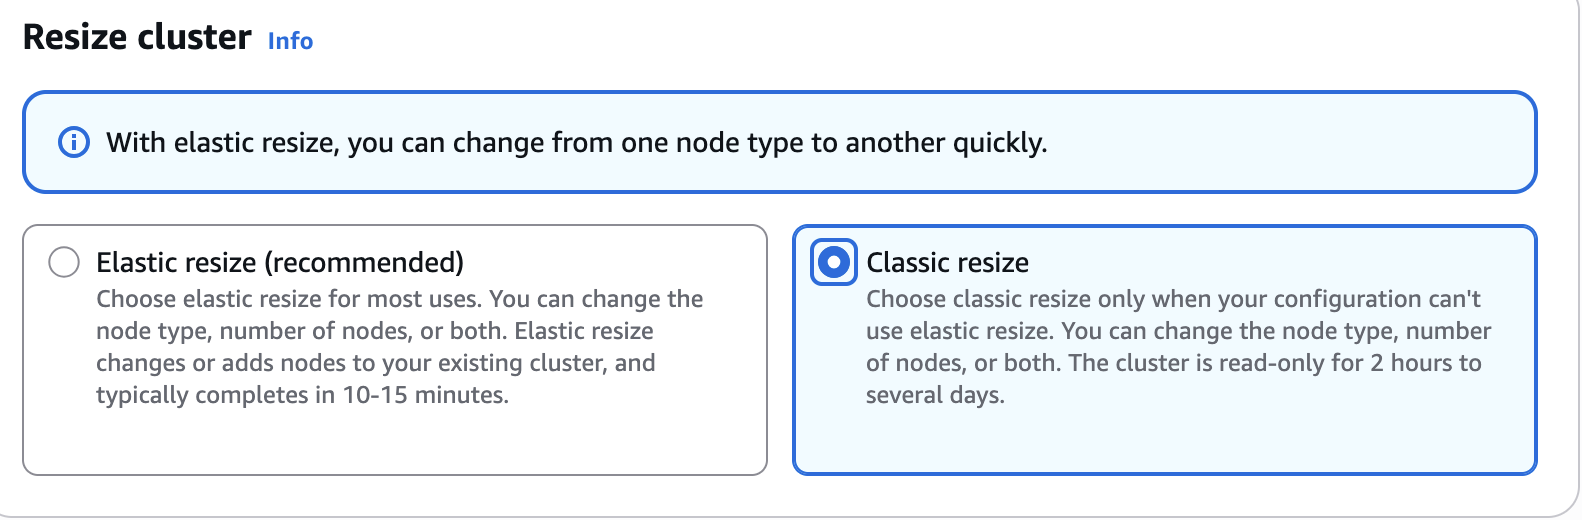
You can use either the console or the following AWS CLI command to initiate a Classic Resize.
To run a Classic Resize through the console, follow the resize instructions in the preceding section and choose Classic resize, as shown in the following screenshot.
To monitor a Classic Resize of a provisioned cluster in progress, including KEY distribution, use SYS_RESTORE_STATE. It shows the percentage completed for the table being converted. You must be a superuser to access the data.
Elastic Resize vs. Classic Resize
Behavior
Elastic Resize
Classic Resize
System tables
Elastic Resize retains system log data.
Classic Resize doesn’t retain system tables and data.
Changing node types
When the node type doesn’t change, Elastic Resize is an in-place resize and most queries are held. With a new node type selected, a new cluster is created and queries are dropped as the resize completes.
A new cluster is created. Queries are dropped during the resize.
Session and query retention
Elastic Resize retains sessions and queries when the node type is the same in the source and target. If you choose a new node type, queries are dropped.
Classic Resize doesn’t retain sessions and queries. Queries are dropped, and you can expect some performance degradation. Run the resize during a period of light use.
Canceling a resize operation
You can’t cancel an Elastic Resize.
For a Classic Resize to an RG or RA3 cluster, you can’t cancel.
Use this method when you need near-constant write access during the migration, or when you want to validate the new RG setup without affecting the existing cluster.
Steps
In the Amazon Redshift console, choose Provisioned clusters dashboard, select your source cluster, choose Actions, then choose Create manual snapshot. Specify a snapshot name and choose Create snapshot.
Select your snapshot.
Choose Restore from snapshot.
Specify the cluster ID and configuration (target cluster).
Verify that the sample data exists in the target cluster by following these steps:
Connect to the target cluster using the new endpoint.
Run SELECT COUNT(*) FROM <table_name> for key tables and compare counts with the source cluster.
Verify that all schemas exist.
Validate that user permissions were restored correctly.
If you write data to the source cluster after taking the snapshot, manually copy the data to the target cluster.
Update your application connection strings to use the new cluster endpoint.
Advantages
Allows validation of the new RG setup without affecting the existing cluster.
Offers flexibility to restore to different Regions or Availability Zones, which provides additional disaster recovery options.
Minimizes the amount of time that the cluster is unavailable for write operations.
Considerations
Setting up the new cluster and restoring data can take longer than Elastic Resize.
Any data written to the source cluster after the snapshot must be copied manually to the target cluster.
A new Amazon Redshift endpoint is created, so connection string changes are required.
To keep the cluster endpoint the same, consider renaming both clusters so the new target cluster has the same name as the original source cluster.
Fallback
You can revert to RA3 at any time using any of the migration approaches described earlier.
DMS, Zero-ETL, and data sharing considerations during migration
If your Amazon Redshift cluster is an AWS Database Migration Service (AWS DMS) target, has Zero-ETL integrations, or is a data sharing producer, keep the following in mind when resizing from RA3 to RG.
AWS DMS change data capture (CDC) tasks aren’t impacted by the resize. The replication instance operates independently and resumes writing after the cluster is available. No task restart is required.
Zero-ETL tables temporarily become unavailable during the resize and enter a resync state. How long the resync takes depends on data volume. Use svv_integration_table_state to check when all tables are back to Synced. For additional details, see Zero-ETL considerations.
When you resize a producer cluster, data sharing is temporarily unavailable while connections transfer to the new cluster. This typically lasts several minutes. Consumer clusters can’t access shared data during this period. After the resize completes, data sharing resumes automatically with no reconfiguration needed. Plan a brief outage window for consumer workloads that depend on the producer being resized.
Snapshot/Restore impact on DMS, Zero-ETL, and data sharing
Zero-ETL integrations are tied to the original cluster. A restored cluster is treated as a new cluster, so replication doesn’t automatically resume. After the restore, you need to create a new Zero-ETL integration pointing to the restored cluster. It performs an initial sync to bring the data current.
AWS DMS connections are endpoint-based. A restored cluster receives a new endpoint, so AWS DMS tasks won’t automatically connect to it. After the restore, you must update the AWS DMS endpoint configuration with the new cluster address and restart the migration tasks.
Data sharing is tied to the cluster namespace. A restored cluster has a different namespace, so existing data shares don’t carry over. As a producer, you need to create new data shares and re-share them with consumer clusters. As a consumer, you lose access until the producer reestablishes the share from the new cluster.
Migration best practices
Inform downstream teams before the migration. This includes data sharing consumers, Zero-ETL applications, and BI/ETL pipelines.
Schedule the migration during a maintenance window to reduce impact on production.
Take a manual snapshot before starting the resize. This serves as your rollback point.
Test your target RG configuration with a representative workload before migrating production.
Confirm that downstream applications are working after completion.
Clean up
To avoid incurring future charges, delete the RG provisioned cluster and any manual snapshots created during migration testing. Deleting a cluster permanently removes all data. Make sure you are deleting only the test cluster. Consider taking a final snapshot before deletion if you need to retain any test data.
Conclusion
In this post, we covered the migration options, considerations, and best practices for upgrading Amazon Redshift RA3 instances to Graviton-based RG instances. For more details on the performance benefits of RG, see the announcement blog post.
Start upgrading to Amazon Redshift RG instances today and take advantage of better price-performance with the guidance in this post. For architectural support or proof of concept (POC) assistance, contact AWS Support.
On June 15 at Fedora’s Flock conference, held in
Prague, Fedora Project Leader (FPL) Jef Spaleta delivered a short “State of
Fedora” keynote that provided a bit of insight into the status of the
project. Topics included the overall growth for Fedora usage, ways to increase
contributions, and an alarming decline in the number of active packagers working
on the project.
Version
152.0 of the Firefox web browser has been released. Notable
changes in this release include a brand-new look for the Firefox
Settings interface, the ability to disable tracker blocking in private
browsing tabs, a feature to mute browser sound from the address bar,
experimental support for the JPEG
XL image format, and more.
Version
6.7 of KDE’s Plasma desktop has been released. Notable changes in
this release include per-screen virtual desktops, faster desktop
switching, introduction of the Union
theming system as a tech preview, as well as many other improvements and bug
fixes. The release is dedicated to Eric Laffoon, a longtime KDE
supporter, who passed away in May.
See the KDE
wiki for a full list of new features, and the Changelog
for a list of all commits in this release.
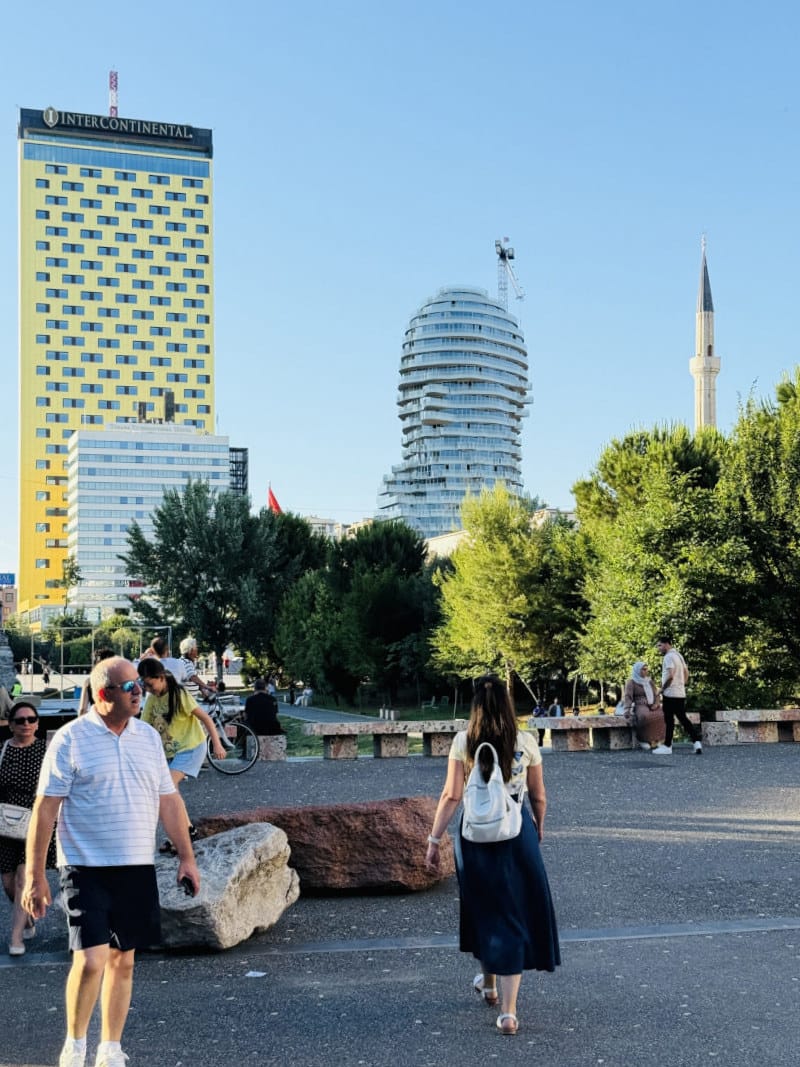
Оказах се в Албания точно в началото на т.нар. Фламингова революция. На 30 май протестиращ беше влачен от охраната на заградена зона в природния резерват до Звърнец, а аз преминах границата с Гърция на път за Тирана и две важни архитектурни събития, които предстояха там през първата седмица на юни. Тогава все още не беше ясно, че протестите ще станат това, което са в момента, а архитектурата ще се окаже буквално в центъра им.
И все пак още в първите дни нещо го подсказваше.
„Аз съм родом от Вльора. Трябва да отидете до Звърнец, там е прекрасно. Искат да го застрояват“, каза ми Арта, собственичка на малък семеен хотел на крайбрежието в Южна Албания. „Е, не протестирате ли?“, попитах аз. „Да, но нищо няма да стане“, отговори тя и се върна в кухнята, където всичко се готвеше с продукти от градината им.
От 15 години само строим. Най-големият ни страх е да не изгоним чуждите инвеститори,
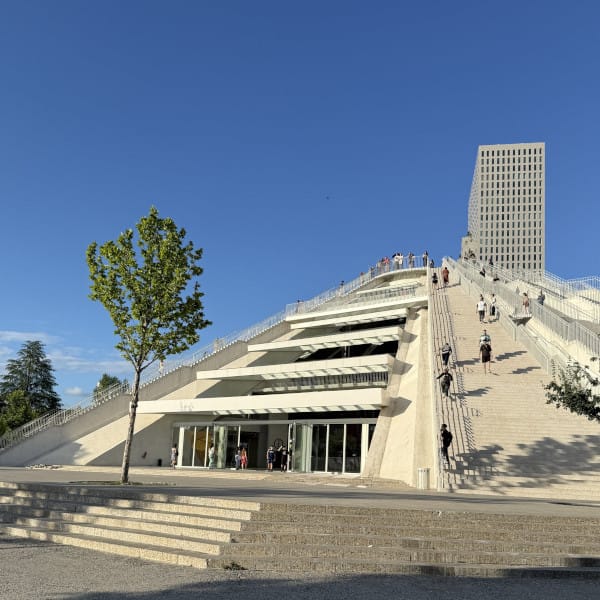
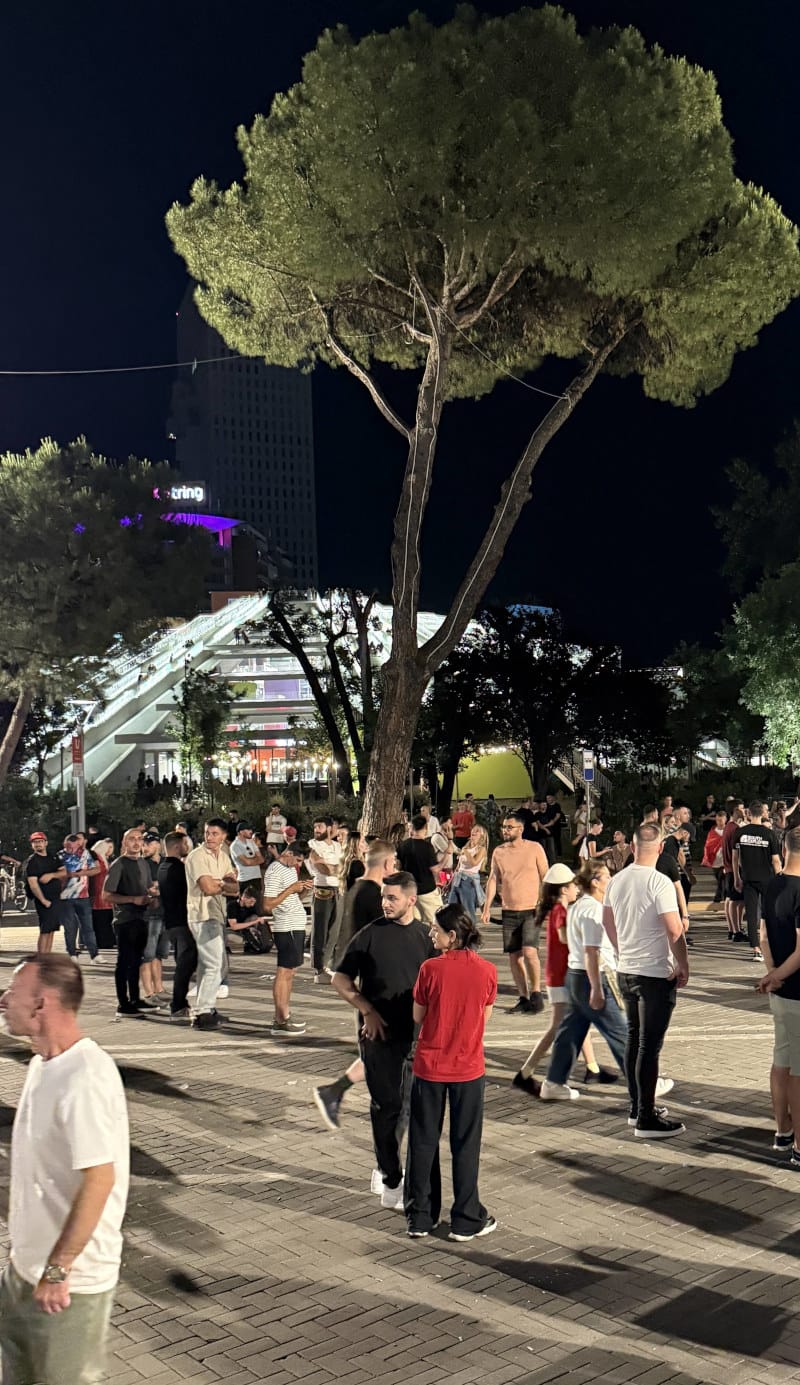
каза ми няколко дни по-късно приятел архитект, вече в Тирана. Протестите бяха започнали, а ние се качвахме по стъпалата на Пирамидата в центъра на града, бивш музей на комунистическия диктатор Енвер Ходжа, а днес стартъп хъб, реконструиран през 2023 г. по проект на холандското суперстудио MVRDV. Беше третият ден на протести, а от върха на пирамидата се виждаше, че хората са наистина много.
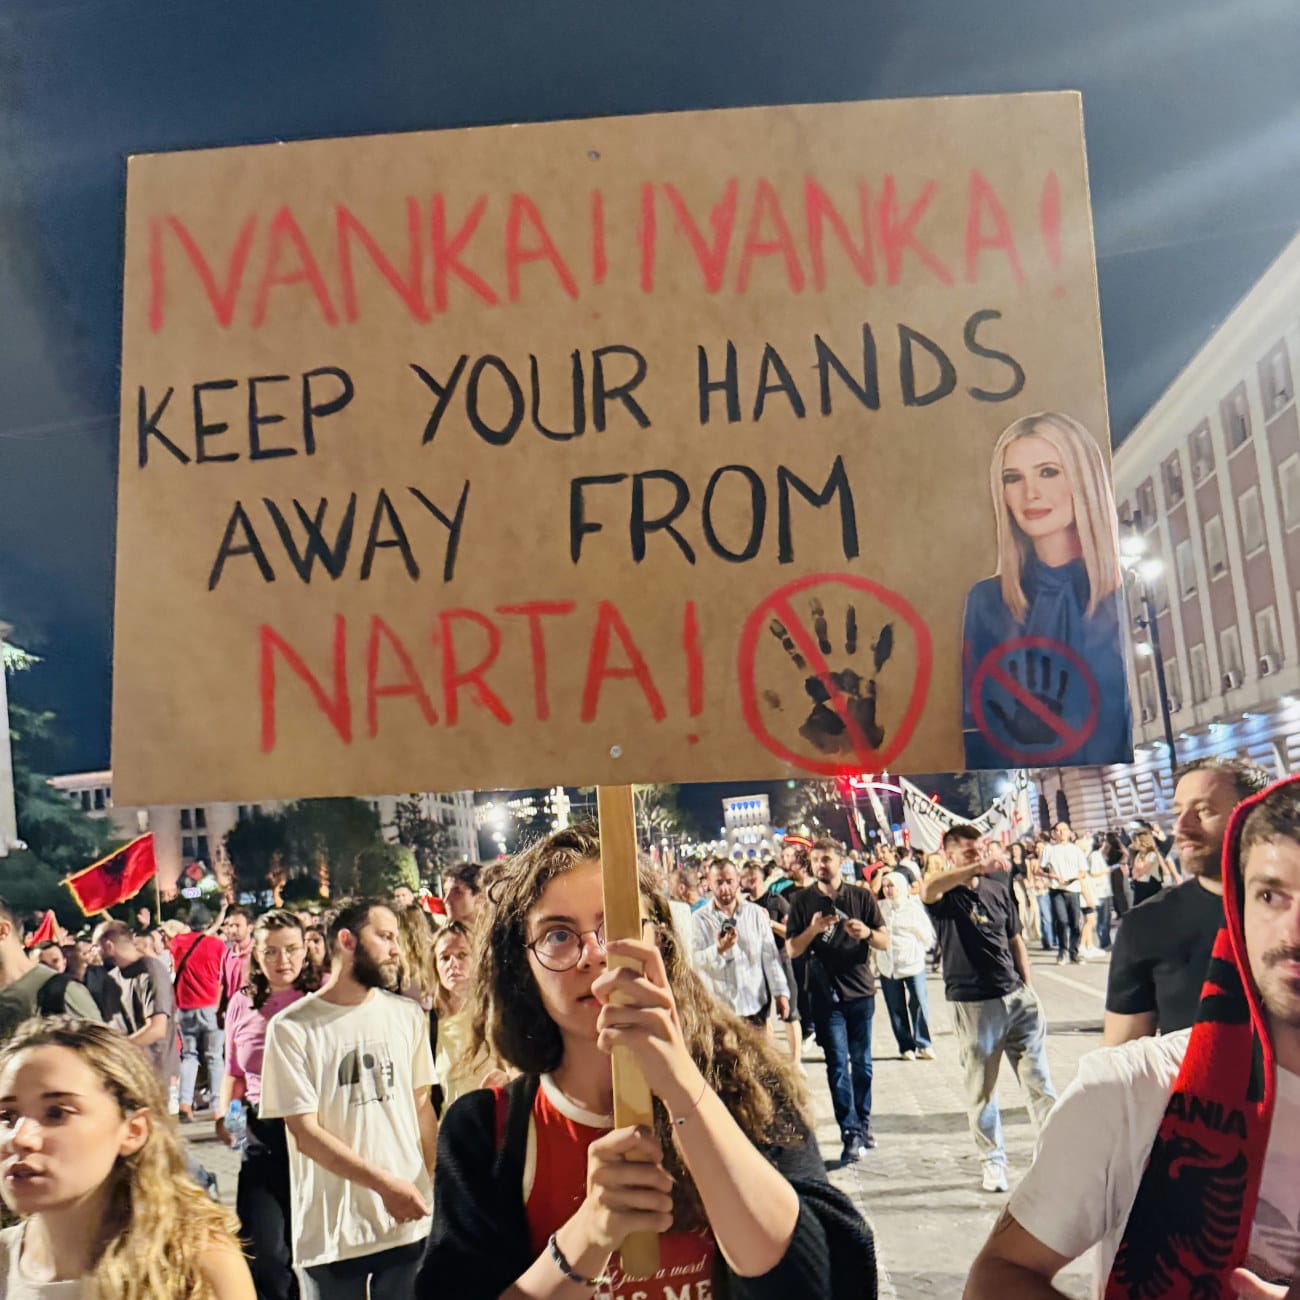
„Видя ли интервюто на Иванка? Скандално. Мисля, че то вбеси хората най-много“, отбеляза Виола, също архитектка, на другата вечер пак в Тирана. Виола е албанка, израснала в Канада, дете на емигранти от 90-те. В момента е университетска преподавателка в Торонто, дошла за същата конференция за опазване на модернизма в Албания като мен. Имаше предвид интервюто на Иванка Тръмп за Дейвид Сенра от края на май, в което дъщерята на американския президент описва своята находка в Средиземно море – необитаемия остров Сазан, на запад от албанския бряг, който със съпруга си Джаред Къшнър „откриват“ съвсем случайно, докато са на яхта на приятели и спират да поплуват. „Плувахме до острова. Изкачихме се пеша, боси чак до върха и просто бяхме очаровани“, казва Иванка. Действително скандално, особено като се има предвид, че островът не е частен, както тя го нарича, а бивша държавна военна база с много стар бетон, по който, освен всичко друго, доста трудно се ходи бос.
Сега ще се опитам да обясня как и защо именно архитектурата е толкова тясно преплетена с политическите вълнения в Албания в момента и всъщност до огромна степен е тяхна първопричина.
Застрояването и Албания
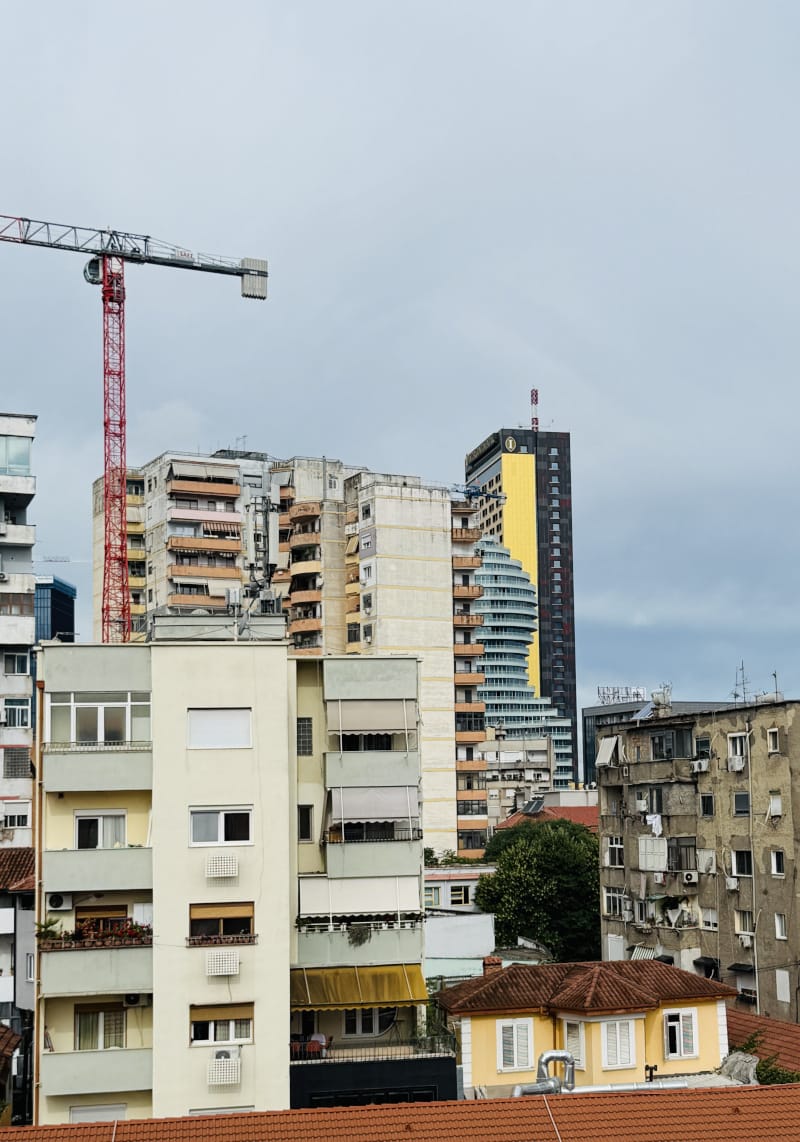
В Албания се строи много – и навсякъде. Усещането е като в България в началото на по-миналото десетилетие, онзи пръв строителен бум, който преживяхме след 2000 г., преди да влезем в Европейския съюз, и който де факто съсипа градовете, планините и черноморското ни крайбрежие.
Строителството е свързано с непоклатимата неолиберална вяра в трансформиращата роля на свободния пазар, която всички бивши комунистически държави в Европа споделят. Разбираемо – след провала на държавния социализъм и сивата пустош, която той оставя навсякъде в края на 80-те. И после идват 90-те, с цялата им мътилка, липса на правила и регулации, с неясния произход на частния капитал, с всички балкански войни, мутри, бедност и кич. Най-неподходящото време, в което да се говори за публично пространство, общество и колективна (архитектурна) отговорност. Строителството е и много успешен начин за пране на пари.
Албания обаче е преживяла много, много повече от България. Страната получава независимост от Османската империя едва през 1912 г. През 1939 г. вече е окупирана от фашистка Италия на Мусолини (италианските архитектурни влияния са видими и до днес). Партизаните комунисти на Енвер Ходжа вземат властта в края на Втората световна война, флиртуват със Сталин, после с Тито, най-дълго с Мао и Китай, за да изолират държавата в края на 60-те от целия свят, включително от Източния блок. И да построят близо 200 000 бункера из цялата страна в параноичен опит да се отбраняват от всички на всяка цена. Балканска версия на Северна Корея, както гласи любимото клише на западните медии, когато пишат за Албания.
Комунистическият режим тук пада най-късно – чак през 1992 г.,
и албанците се втурват да емигрират – първо към Италия, а оттам и към целия най-после отворен свят. Останалите в страната първо започват да купуват коли (през 1992 г. в Тирана има само 200 леки автомобила), а после да строят – навсякъде. Приватизацията на държавната собственост е още по-тъмна и хаотична, отколкото в България, и през 90-те не е ясно коя земя на кого е, затова всички строят където им падне – магазини, бараки, къщи, ресторанти – всичко. Качеството е ужасно, градовете (и особено Тирана) не приличат на нищо.
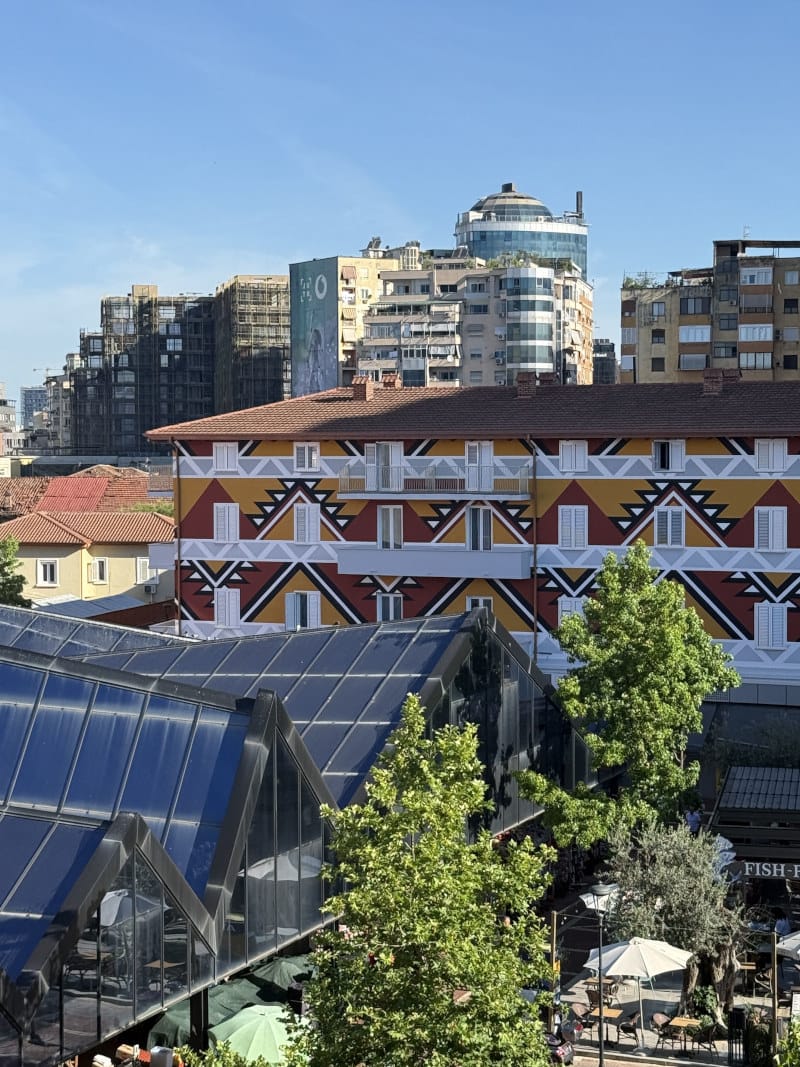
И тук на сцената излиза главният герой в албанския политически живот и до днес – художникът Еди Рама, който става кмет на Тирана през 2000 г. Той заварва посткомунистически хаос с куп незаконни сгради, висока престъпност, никакви публични пространства, проблеми с боклука и канализацията и много сиви сгради навсякъде. Рама става международно популярен с радикалното си решение да боядиса целия град в ярки цветове – евтино и ефектно, а и логично за един художник, който познава психологията на цветовете. Отделно, той събаря хиляди незаконни постройки и изчиства от тях бреговете на река Лана, за да създаде нови паркове и обществени зони. Няколко пъти го пребиват.
Изобщо – герой. Рама става любимец на световните медии, на лъскавите списания за архитектура, дизайн и градски живот, а през 2004 г. печели международната награда „Кмет на годината“. Той е лице на неолиберализма на Балканите, оглавява Социалистическата партия на Албания, приятел е с Тони Блеър, обявява, че страната ще се развива прогресивно и по трети път – без ляво и дясно.
През 2020 г. албанският архитект и преподавател Саймир Кристо много добре описва ситуацията с Тирана и цветовете на Рама в една своя статия за холандския архитектурен портал Archined:
Това не е наивен опит да се разведрят жителите на Тирана, за да забравят авторитарния режим, който е властвал почти половин век. В крайна сметка никога не се започва от нулата след падането на един режим. Днес в Тирана по-скоро наблюдаваме директния западен маниер да се представят посткомунистическите страни като сиви, а капитализмът и развитието – като „жизнени“ и „цветни“.
Еди Рама и архитектурата
Днес Еди Рама е министър-председател на Албания за четвърти пореден мандат и е обещал страната да влезе в Европейския съюз до 2030 г. А основното му оръжие за международен престиж, привличане на чуждестранни инвеститори, развитие на туризма и икономиката и преобразяване на страната е едно – архитектурата. Еди Рама обича архитектурата и обожава световноизвестните архитекти.
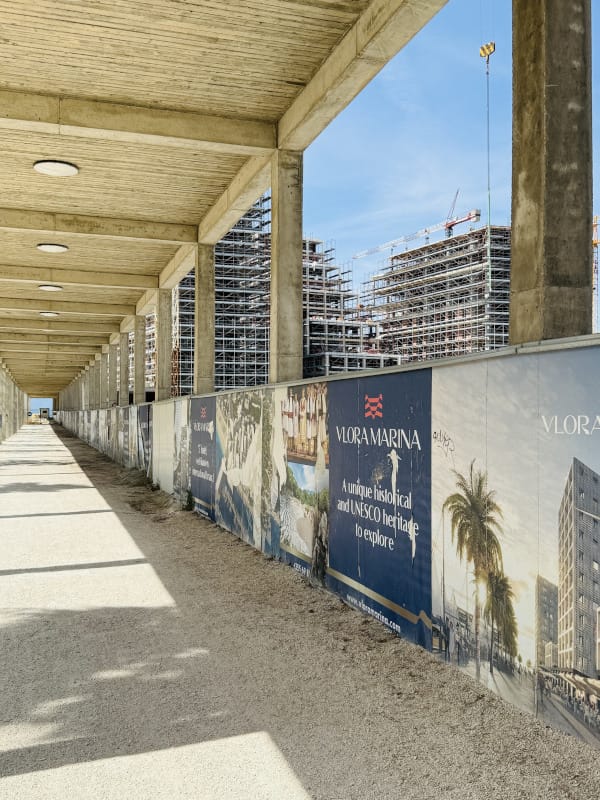
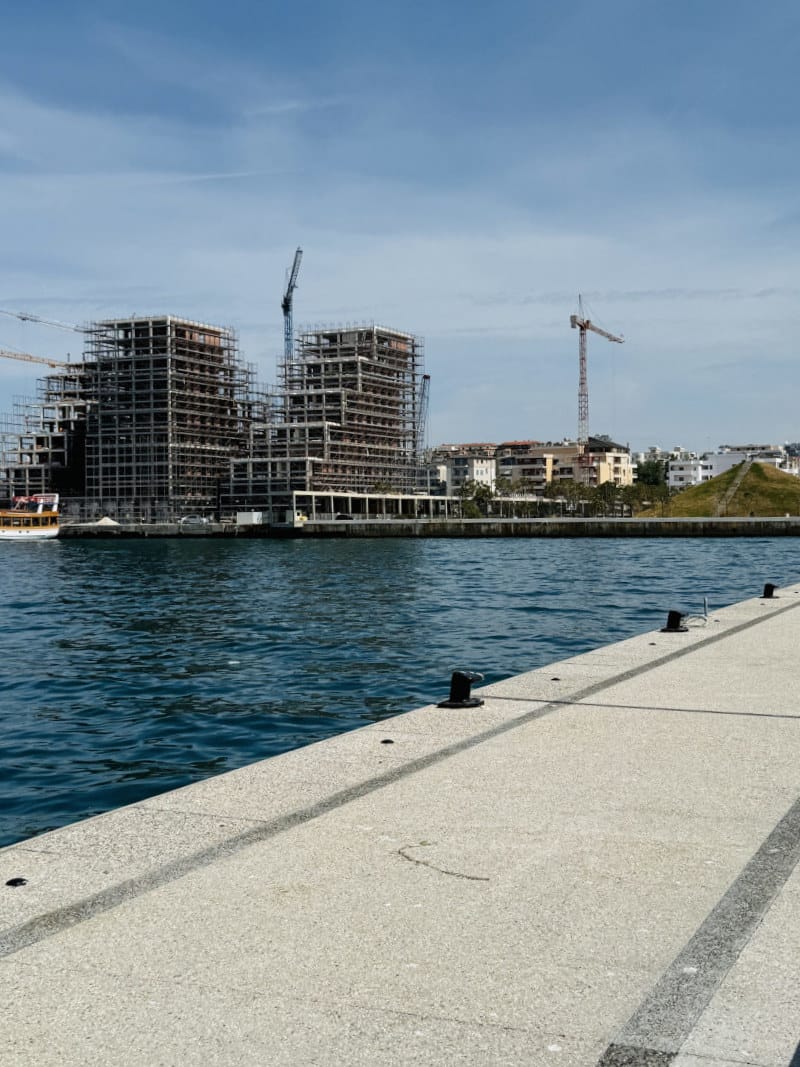
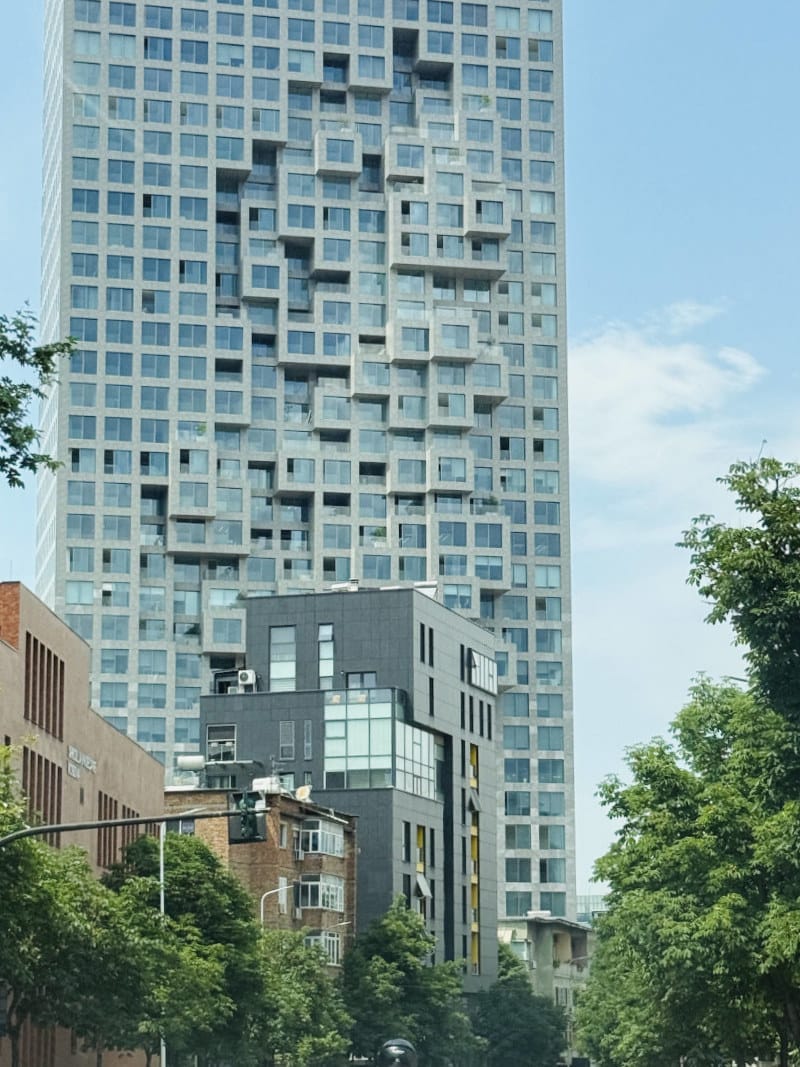
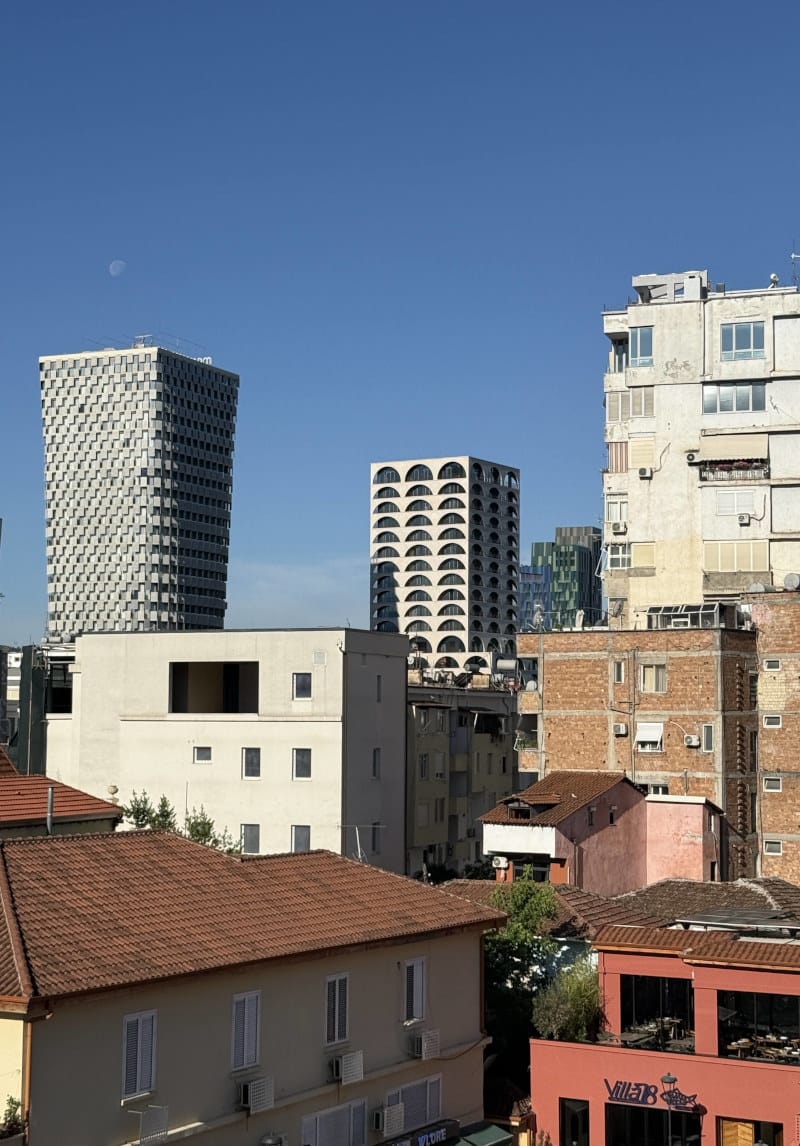
От 2008 г., когато белгийското студио 51N4E печели международния архитектурен конкурс за реконструкция на централния площад „Скендербег“ в Тирана, до ден днешен градът е истинска площадка за игра на архитектите от цял свят. И нямам предвид само поувехналите стархитекти (т.нар. архитекти звезди на миналото), а всички, включително „социално отговорните“ сред тях. През 2019 г. Общинският съвет на Тирана одобрява новия общ устройствен план на града, разработен от италианското студио Stefano Boeri Architetti и кръстен неслучайно „Тирана 2030“. Планът предвижда компактен полицентричен град с много нови публични пространства, линейни паркове и екологични коридори, 2 млн. нови дървета и всички модни думи на съвременното градоустройство. Той отприщва безпрецедентен строителен бум, който превръща Тирана в град на кули и купища нови строежи, докато се задъхва в задръствания и липса на паркоместа.
В момента в столицата се проектират, строят или имат разрешение за строеж над 140 небостъргача
на принципа на наложеното от Еди Рама публично-частно партньорство. Албанските архитекти са изключени от процеса. Те чертаят техническите проекти, обслужват разрешенията за строеж и критикуват властта, че инвестира в нови публични пространства не заради жителите на Тирана, а за да повишава пазарната стойност на новите частни инвестиции из града. Легендарен е списъкът на Еди Рама с над 150 чуждестранни архитектурни студиа, измежду които той избира на кого какви проекти да възлага. Особена е слабостта му към популярни архитекти и носители на наградата „Прицкер“, а всички те нямат нищо против да играят ролята на придворни проектанти на албанския „владетел“.
В интерес на истината, всички тези нови сгради са безкрайно интересни и в момента Тирана е колоритна мозайка от всякакви стилове и архитектурни похвати на фона на хаотично-еклектичното си постсоциалистическо наследство. На всичко отгоре новите сгради и пространства са проектирани добре, повечето са изпълнени отлично. Взети сами за себе си, са чудесни примери за съвременна архитектура с ниво на детайл и качество на изпълнение, за които съвременната българска архитектура може само да мечтае. Всъщност тя си мечтаеше точно за същото някъде около 2008 г., когато стартира първата Седмица на архитектурата у нас (т.нар. Sofia Architecture Week – SAW) – затворено платено събитие за инвеститори, институции и международни архитекти, което да даде старт на една друга София на визии, конкурси и чуждестранни архитектурни проекти.
Но не се получи. За добро или за лошо, в София така и няма сграда или примерно площад на „световноизвестен архитект“. А усилията на целия екип на списание ЕДНО и SAW да убедят българската власт, че си струва да се инвестира в звездна архитектура и дизайн, така и не хванаха на каменистата българска почва поради липса на местен Еди Рама. Може би е било за добро.
Защото през първата седмица на юни в Тирана ме беше срам, че съм архитект от чужбина.
Точно тогава Еди Рама посрещна световния архитектурен елит – буквално всички, за които човек може да се сети – на второто поредно издание на фестивала Bread and Heart. Събитието беше в Book Building, последната кула, проектирана от белгийските любимци на Рама 51N4E до площада „Скендербег“. Албанските архитекти по принцип бойкотираха форума. И как не – от години те се чувстват сведени до чертожници на чужденците. Намерих само една местна позната, която беше посетила целия форум и която сподели:
Аз ги питах какво мислят за корупцията и за протестите, за презастрояването и проблемите, а те ми казаха: „Ние какво можем да направим, дошли сме тук да проектираме и да строим. Вашите неща си ги оправяйте вие, ние нищо не можем да направим.“
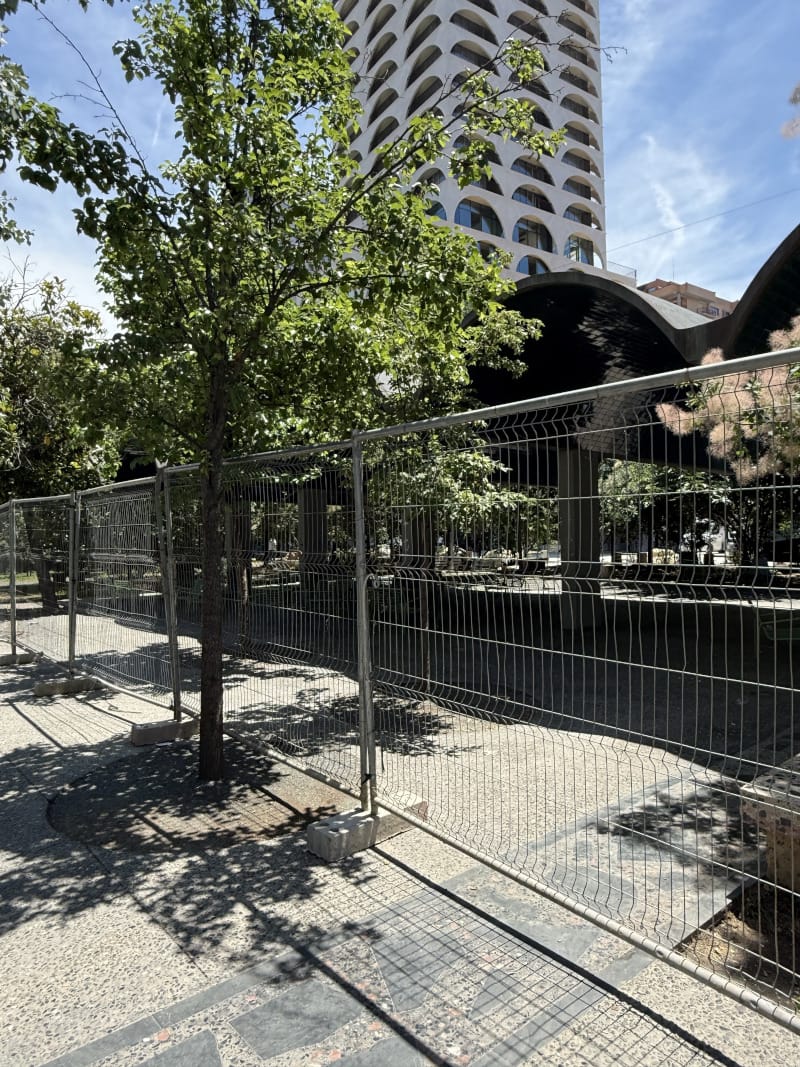
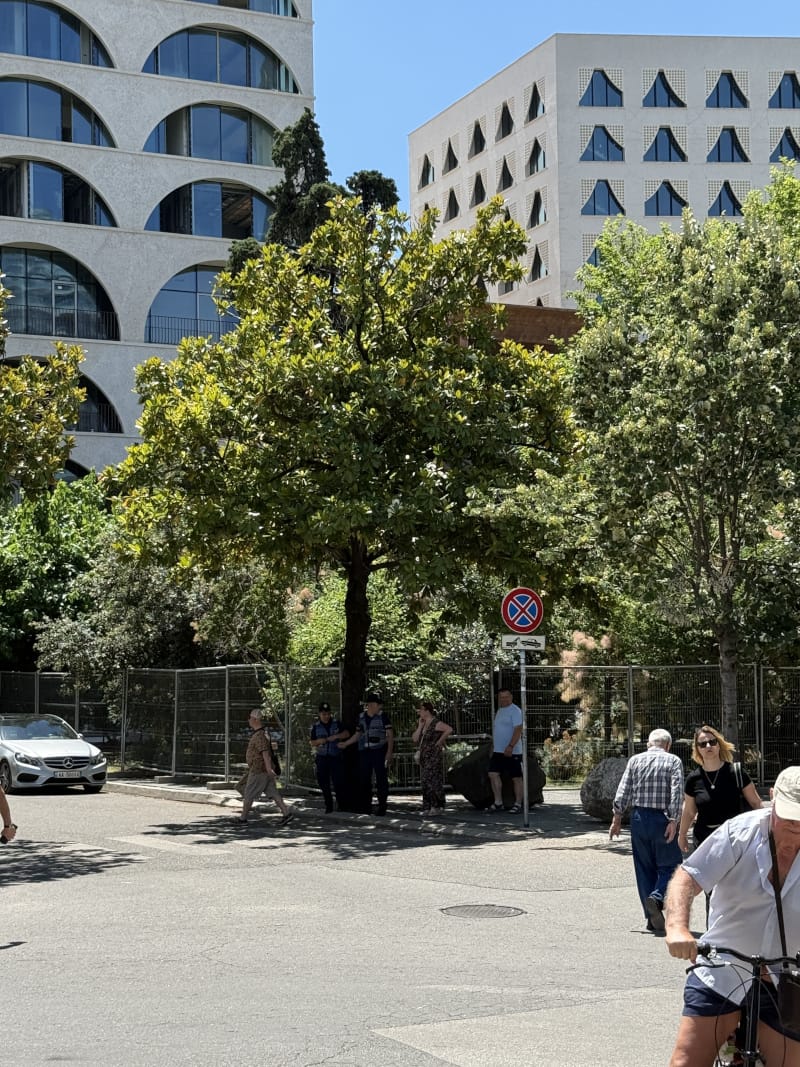
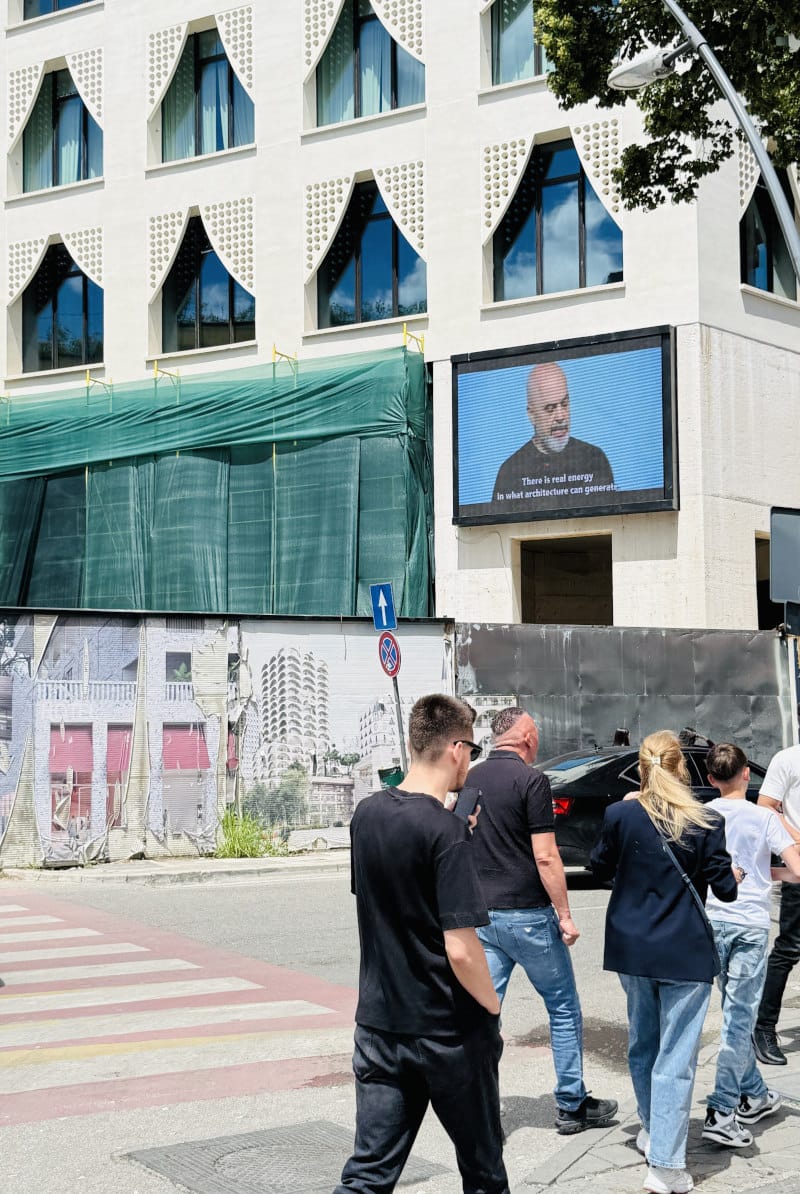
Интересното беше, че достъпът до цялата сграда беше блокиран, ограждения прекъсваха пешеходното движение към площада, а полицаи пазеха архитектурния елит от любовта на тълпата. Защото през първите дни на протестите в Тирана те завършваха именно пред Book Building и освиркваха не само екрана с образа на Рама, опънат на един от ъглите на сградата и предаващ на живо, но и архитектите вътре. Архитектите, които обслужват чужденците, които ще застроят тяхната Албания. „Еди Рама е свършен!“ беше единият от най-популярните възгласи тогава. Другият – „Албания не е за продан!“.
А сега да се върнем на протестите.
Edi Rama ka mbaru, ka mbaru!1
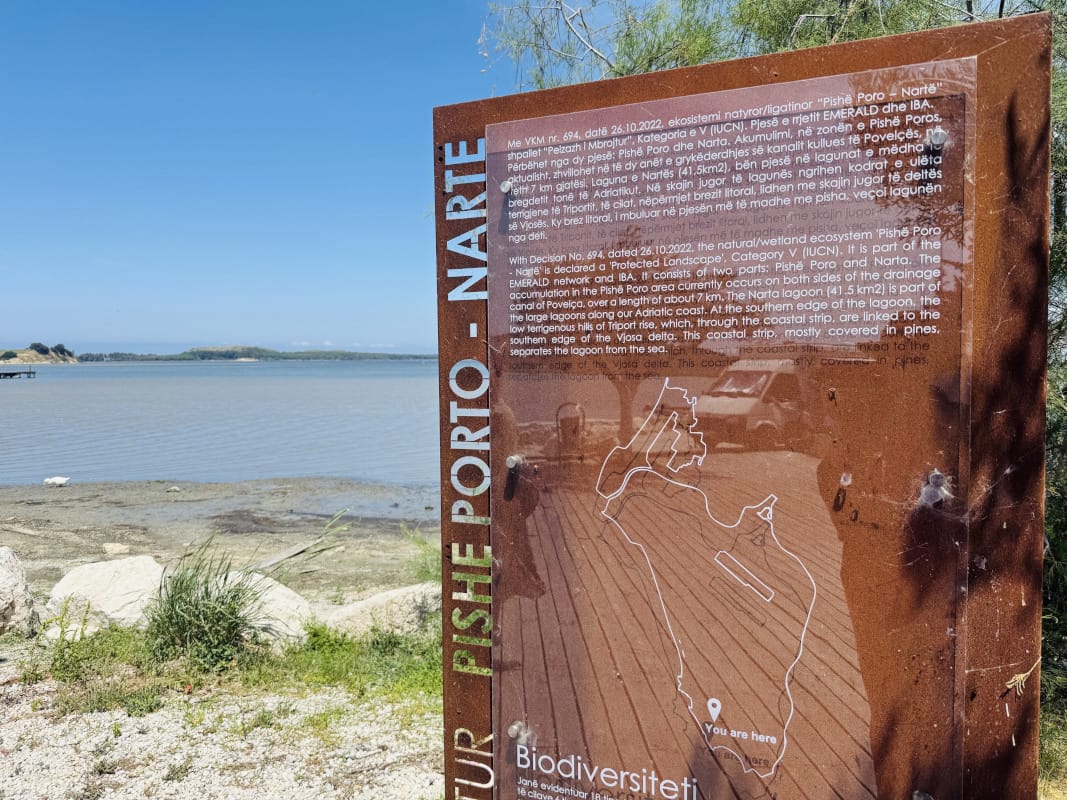
Големите протести в Албания започнаха в началото на юни като екологични – срещу намеренията за строителство на луксозен курорт в защитените природни зони на остров Сазан и лагуната Вьоса-Нарта – ценна средиземноморска влажна зона, която предоставя убежище на над 200 вида птици и повече от 70 застрашени вида. Инвестицията се свързва с имената на Иванка Тръмп и съпруга ѝ Джаред Къшнър. Зад нея стоят няколко компании с неясни или криминални собственици, а проектът получава предварително одобрение като стратегическа инвестиция от албанското правителство през декември 2025 г. Междувременно защитената зона е намалена като обхват, а през 2021 г. е разрешено в района да се изгради летище. Еди Рама подкрепя проекта, който е оформен като обичайното публично-частно партньорство, тъй като островът все още е държавен, но брегът вече е частен.
Следват разкрития за устройствени и архитектурни планове за курорта от ноември 2025 г., които вбесяват още повече протестиращите заради стотиците хиляди квадратни метри застроена площ, които се предвиждат, хилядите жилища и хотелски стаи и визията за затворен ултралуксозен резерват само за свръхбогати. За няколко дни протестите се разраснаха в пъти, състояха се и в други градове освен Тирана и Звърнец, хората излизат на улицата ежедневно, а тълпата в Тирана расте с всеки следващ ден. Това вече са политически протести – за оставката на Еди Рама и цялото правителство, срещу целия управляващ елит, включително срещу опозиционния лидер Сали Бериша, който подкрепя курорта.
Архитекти в Тирана ми пишат, че последните дни протестите са станали и националистически – именно като реакция срещу чуждестранните инвеститори, които правителството на Рама толкова цени, и защото „Албания не е за продан“.
Архитектурата и властта
За мен е важно да осъзнаем ролята на архитектурата като инструмент на властта – за пореден път болезнено оголена и в този албански случай.
Еди Рама е лицето на либералната демокрация – такава, каквато я познаваме от Клинтън и Обама, на онази американска Демократическа партия, която загуби последните избори и отвори път към една съвсем различна Америка. Това, което се случва в Тирана и Албания в момента, е като надгробен камък на неолиберализма от първите две десетилетия на нашия век. Точно като библиотеката „кенотаф“ на Барак Обама в Чикаго, която отвори врати този същия юни под канонада от критики. Стархитектите вече са в миналото. Големите студиа отмират. Необходимо е адаптивно преизползване на ресурси. В същото време има потребност от качество и отношение – към средата, към хората, към контекста. Арогантната архитектурна самоувереност е неадекватна за времето ни, архитектурното его само пречи, а лицемерието винаги излиза наяве – рано или късно.
Именно срещу това реагираха ожесточено албанските архитекти по време на фестивала Bread and Heart в Тирана. Под бляскавите постове в социалните мрежи за изминалите дни на „вдъхновение и споделени идеи“, чиито автори очевидно не чуваха гласовете на тълпата под прозорците на Book Building, те пишеха гневни коментари в социалните мрежи, които биваха изтривани.
Завършвам с един такъв изтрит коментар на албанската архитектка и преподавателка Мамица Бурда:
Всички говорят за деколонизация, отстояване на пространства, отказ от растежа, регенерация, пространствена справедливост, колективна грижа, общи блага, общности, адаптивно преизползване, бъдеще без въглеродни емисии и други модни концепции. Веднага щом човек започне да работи в бедни страни с висока степен на корупция и пране на пари обаче, принципите изведнъж се променят. Албания определено е лакмус за съвременната архитектурна практика. Тя показва дали архитектите наистина отстояват ценностите, които пропагандират – социална отговорност, устойчивост и обществен интерес, – или тези принципи изчезват, когато се сблъскат с възможност за печалба и популярност.
1 „Еди Рама е свършен, свършен е!“ (алб.) – най-често скандираният възглас в първите дни на протестите в Тирана.
When we first launched DMARC Management, it was driven by a simple belief: every domain on the Internet deserves strong email authentication, and cost should never be the reason it doesn’t happen. As part of our mission to help build a better Internet, we made DMARC Management available for free to every Cloudflare customer. We wanted to give everyone the tools to understand and improve their DMARC posture without needing to hire an email security consultant or parse XML report files by hand.
Today, we are taking that commitment further. Cloudflare DMARC Management is now generally available, with a redesigned experience built to help you reach full DMARC enforcement as easily as possible.
The DMARC Management dashboard offers a unified view of your email authentication posture.
What email authentication actually does for you
Every time someone receives an email “from” your domain, their email provider asks a simple question: did the real owner of this domain actually send this? Without a way to answer that question, anyone can send an email pretending to be you and your recipients will have no way to tell the difference.
Email authentication is the set of DNS records that answers that question. There are four protocols that protect your domain:
SPF (Sender Policy Framework) tells receiving mail servers which IP addresses and services are allowed to send email on behalf of your domain.
DKIM (DomainKeys Identified Mail) attaches a cryptographic signature to every email you send, so receiving servers can verify the message hasn’t been tampered with in transit.
DMARC (Domain-based Message Authentication, Reporting, and Conformance) ties SPF and DKIM together and tells receiving servers what to do when an email fails authentication: let it through, quarantine it, or reject it outright. It also sends you reports on who is sending email as your domain.
BIMI (Brand Indicators for Message Identification) lets you display your brand logo next to your emails in supported inboxes, but only if your DMARC policy is strong enough.
When all four are configured correctly, spoofed emails get blocked before they reach anyone’s inbox and your legitimate emails are far more likely to be delivered. When they’re missing or misconfigured, you’re exposed to brand impersonation and deliverability penalties from the large email mailbox providers.
DMARC is no longer optional
DMARC has always been important. But over the past two years, the stakes have gotten significantly higher. Google, Microsoft, and Yahoo have all announced or implemented stricter email authentication enforcement. Domains that do not have proper DMARC, SPF, and DKIM records configured (or worse, have them configured incorrectly) are increasingly seeing their legitimate emails land in spam folders or get rejected outright. What was once a best practice is now a requirement. Poor email hygiene directly translates to poor deliverability, and for many businesses, that means lost revenue and missed communications.
The message from the industry is clear: if you send email from your domain, you need these records configured correctly. The grace period is over.
The problem: DMARC is confusing, and mistakes are costly
Here is the challenge. The journey from p=none (monitor only, no emails are blocked) to p=quarantine (suspicious emails are sent to spam) to p=reject (unauthenticated emails are blocked outright) is filled with uncertainty. Enable enforcement too early, and you risk breaking legitimate email flows from third-party services you forgot were sending on your behalf. Move too slowly, and you leave your domain exposed to spoofing, and now, to deliverability penalties from the very providers your customers use.
Most organizations know they need DMARC enforcement. But actually getting there requires understanding aggregate XML reports, identifying every legitimate sending source across your infrastructure, and building enough confidence that tightening your policy will not break anything.
We built Cloudflare DMARC Management so that any customer can navigate this journey on their own. No need for professional services engagement. No spreadsheet analysis of aggregate reports. No guessing which IP address belongs to which vendor. The goal is to make the path to full DMARC enforcement as self-service as possible, giving you the visibility and confidence to tighten your policy without breaking anything.
DMARC reports show sending source alignment across your domain.
What we shipped
Deeper report visibility with source investigation
We redesigned the reporting experience to make it easier to understand what is happening with your email traffic. You can now see at a glance which sending sources are passing or failing DMARC, SPF, and DKIM alignment and drill deeper than ever before.
Every report now surfaces the source IP address alongside the sending service, giving you the granularity to distinguish between legitimate infrastructure and unauthorized senders. You can now open any IP address directly in our Investigate tab, which surfaces all the threat intelligence Cloudflare has on that address — reputation data, geolocation, autonomous system number (ASN) details, and any known associations with malicious activity.
This turns your DMARC reports from a passive data feed into an active investigation tool.
Drilling into a sending source reveals IP-level detail and Cloudflare threat intelligence in the Investigate tab.
What you see
What it tells you
Source IP address
The specific infrastructure sending email on behalf of your domain
Sending service name
The organization or provider behind the IP
DMARC / SPF / DKIM alignment
Whether each authentication check passed or failed for that source
Investigate tab
Cloudflare threat intelligence: reputation, geolocation, ASN, and known threat associations
Email authentication record status
One of the most common questions customers ask is: “Are my records set up correctly?”
Until now, answering that question required manually inspecting DNS TXT records and understanding what each tag and value means across multiple specifications. With this release, you can see the status of every email authentication record you need: DMARC, DKIM, SPF, and BIMI, in a single view.
Each record type gets a clear pass, warning, or fail status based on automated analysis. You can drill into any record to see specific findings about what we detected and recommendations for how to fix it. If your DKIM key is malformed, we flag it. If you are missing a BIMI record and your DMARC policy is strong enough to support one, we let you know that too.
Record analysis cards show pass, warning, or fail status for each email authentication record, with actionable recommendations.
The recommendations are written in plain language, not RFC jargon. The goal is to make it obvious what action to take next, regardless of your email security expertise.
Policy strength, monitoring vs. enforcement, reporting configuration
BIMI
Logo URL format, Verified Mark Certificate (VMC) presence
SPF lookup audit
This one addresses a problem that silently breaks email for more organizations than you would expect. The SPF specification (RFC 7208) imposes a hard limit of 10 DNS lookups per SPF evaluation. Every include:, a, mx, redirect, and exists mechanism in your SPF record counts toward that limit, and so do the nested lookups inside each include:. Exceed 10 and receiving mail servers return a permerror, which means your SPF check fails entirely.
Most people have no idea they are over the limit until their email starts getting rejected.
DMARC Management now lets you audit your SPF record and see exactly how many lookups it incurs. You can drill into every mechanism in the record, see which include:chains are the most expensive, and identify where to consolidate or flatten your record to get back under the limit.
The SPF lookup audit traces every DNS lookup in your SPF record, showing exactly where you are against the 10-lookup limit.
Getting started
To use DMARC Management, you need to have your domain’s DNS on Cloudflare. Then you can turn on DMARC Management under the Email tab for that domain in the Cloudflare dashboard.
1. Navigate to your domain in the Cloudflare dashboard.
2. Go to Email > DMARC Management.
3. Follow the setup wizard to start receiving DMARC reports.
4. Review your record analysis and recommendations.
5. Work toward p=quarantine (suspicious emails go to spam) or p=reject (unauthenticated emails are blocked entirely) at your own pace.
What’s next
We are going to continue building on top of DMARC Management, and our goal is to keep it accessible. We have several things planned that we are excited to ship: deeper forensic reporting, smarter recommendations, and tighter integration with the rest of the Cloudflare platform.
If you are not yet using Cloudflare for your DNS, you can get started here. Once your domain is on Cloudflare, DMARC Management is available immediately with no additional configuration or cost required.
Your domain is either protected or it isn’t. Head to Email > DMARC Management in your Cloudflare dashboard to get started.
The UK Government is undertaking the first major review of England’s curriculum and qualifications system since the current national curriculum was introduced in 2014. We believe that this is an excellent opportunity not simply to update the computing curriculum content, but to reconsider what computing education is for, who it serves, and how it prepares young people for life in a digital society.
Putting students and teachers at the heart of the conversation
Too often, curriculum reform happens around students and teachers rather than with them. Yet these are the people who experience computing education every day, and they have valuable insights into what is working, what is not, and what needs to change.
Our new report is based on a series of student focus groups and teacher workshops held by us and the University of Cambridge in Manchester, London, and Cambridge during spring 2026.
The student discussions included young people currently studying computer science at GCSE and A level (ages 14–18), as well as young people who had decided to not continue with the subject. We also brought together 18 computing teachers from secondary schools across England to explore curriculum priorities and challenges for implementation.
Although participants in our workshops had differing perspectives, they consistently pointed to the same underlying challenge: the current curriculum no longer reflects the realities of technology, work, or young people’s lives.
“AI is everywhere now, we need to understand how it works, not just be told not to use it.” – Student, London
In particular, many students highlighted a lack of confidence in their practical digital skills despite using technology constantly in everyday life.
“I can code a bit, but I don’t know how to use Excel properly, that’s what I’ll actually need.” – Student, London
Calls for a practical, relevant, inclusive, and future-facing curriculum
Students and teachers are not calling for a less rigorous curriculum. Nor are they arguing that computing should lose its technical foundations, with teachers consistently emphasising the value of understanding computational thinking, programming, algorithms, data, and computer systems and networks.
Instead, students and teachers want to make computing education more practical, relevant, inclusive, and future-facing.
Teachers particularly emphasised the importance of helping students understand how AI systems function, including issues such as bias, training data, limitations, and ethical implications. Participants argued that computing education should help young people understand the technologies shaping their lives, not simply prepare them for examinations. Perhaps the strongest area of agreement was that curriculum reform will only succeed if it is matched by investment in teaching.
Six key priorities for curriculum reform
Based on our discussions with students and teachers, we have identified several priorities for curriculum reform.
1. Guarantee a core digital education for every young person
All students should leave school with a strong foundation in digital literacy, online safety, data awareness, and AI literacy. These should be treated as essential components of modern education, not optional extras.
2. Modernise curriculum content
The curriculum should focus on contemporary technologies and concepts, including AI, cybersecurity, and data, while trimming content that is overly specific, outdated, or disconnected from modern practice. Foundations such as programming, algorithms, and computational thinking should remain central.
3. Prioritise practical and applied learning
Computing should be taught through making, experimentation, and problem solving. Project-based learning, physical computing, and relevant, real-world applications should become central approaches across all ages.
4. Introduce greater flexibility and specialisation
The revised curriculum should balance a shared foundation with opportunities for students to specialise in areas aligned with their interests and aspirations.
5. Embed inclusion throughout the curriculum
Any reforms should actively address barriers to participation by ensuring inclusive teaching approaches, diverse, relatable role models, and accessible learning experiences.
6. Invest in teachers and implementation
Curriculum reform must be accompanied by sustained investment in teacher recruitment, professional development, and classroom resources. Without this, reforming the curriculum risks widening existing inequalities in provision.
Read our full report
We believe listening to students and teachers should be central to curriculum reform. You can read the full report now:
There are over a dozen cases around the country where police officers are using the Flock surveillance camera system to obsessively and illegally stalk people.
AWS WAF now includes AI traffic monetization capability that gives digital content owners and publishers a way to charge AI bots and agents for access to protected web content directly at the network edge. The capability helps content owners and publishers set per-request pricing by content path, bot category, or verification tier without modifying their origin infrastructure or writing application code. Content owners can define granular access policies per agent type, collect payments in stablecoins to their preferred wallet, and monitor revenue and bot activity from a single dashboard.
AI bot traffic now accounts for more than 50% of web traffic for many content providers, with AI-specific crawlers growing more than 300% year-over-year. Unlike traditional search engine crawlers, which index content and return measurable referral traffic back to publisher websites, AI bots consume the same content to generate summaries and responses in AI interfaces, with little to no traffic sent back to the original source. Publishers bear the infrastructure costs of serving that traffic without the page views, ad impressions, or subscription conversions that typically offset those costs. AWS WAF Bot Control already gives customers visibility into bot activity and the ability to block or rate-limit traffic, but setting pricing and collecting payment from AI agents has not been possible until now. AI traffic monetization is a new Bot Control capability that closes that gap, giving content owners and publishers a way to configure pricing rules directly through the AWS WAF console and collect payments from AI agents through third-party payment integrations, without building custom payment infrastructure or negotiating individual licensing agreements. Payment settlement and verification flows are provided by Coinbase’s x402 Facilitator. Integration with Stripe for direct account payments and Machine Payments Protocol (MPP) support is coming soon.
Getting Started with AI Traffic Monetization Before configuring monetization, confirm that AWS WAF Bot Control is enabled at Common or Targeted level on the web ACL associated with your CloudFront distribution. Bot Control provides the agent classification that monetization rules depend on. If you have not set this up yet, visit Adding the AWS WAF Bot Control managed rule group to your web ACL documentation. In the AWS Management Console, go to WAF & Shield and choose Protection packs (web ACLs) in the left navigation pane to get started.
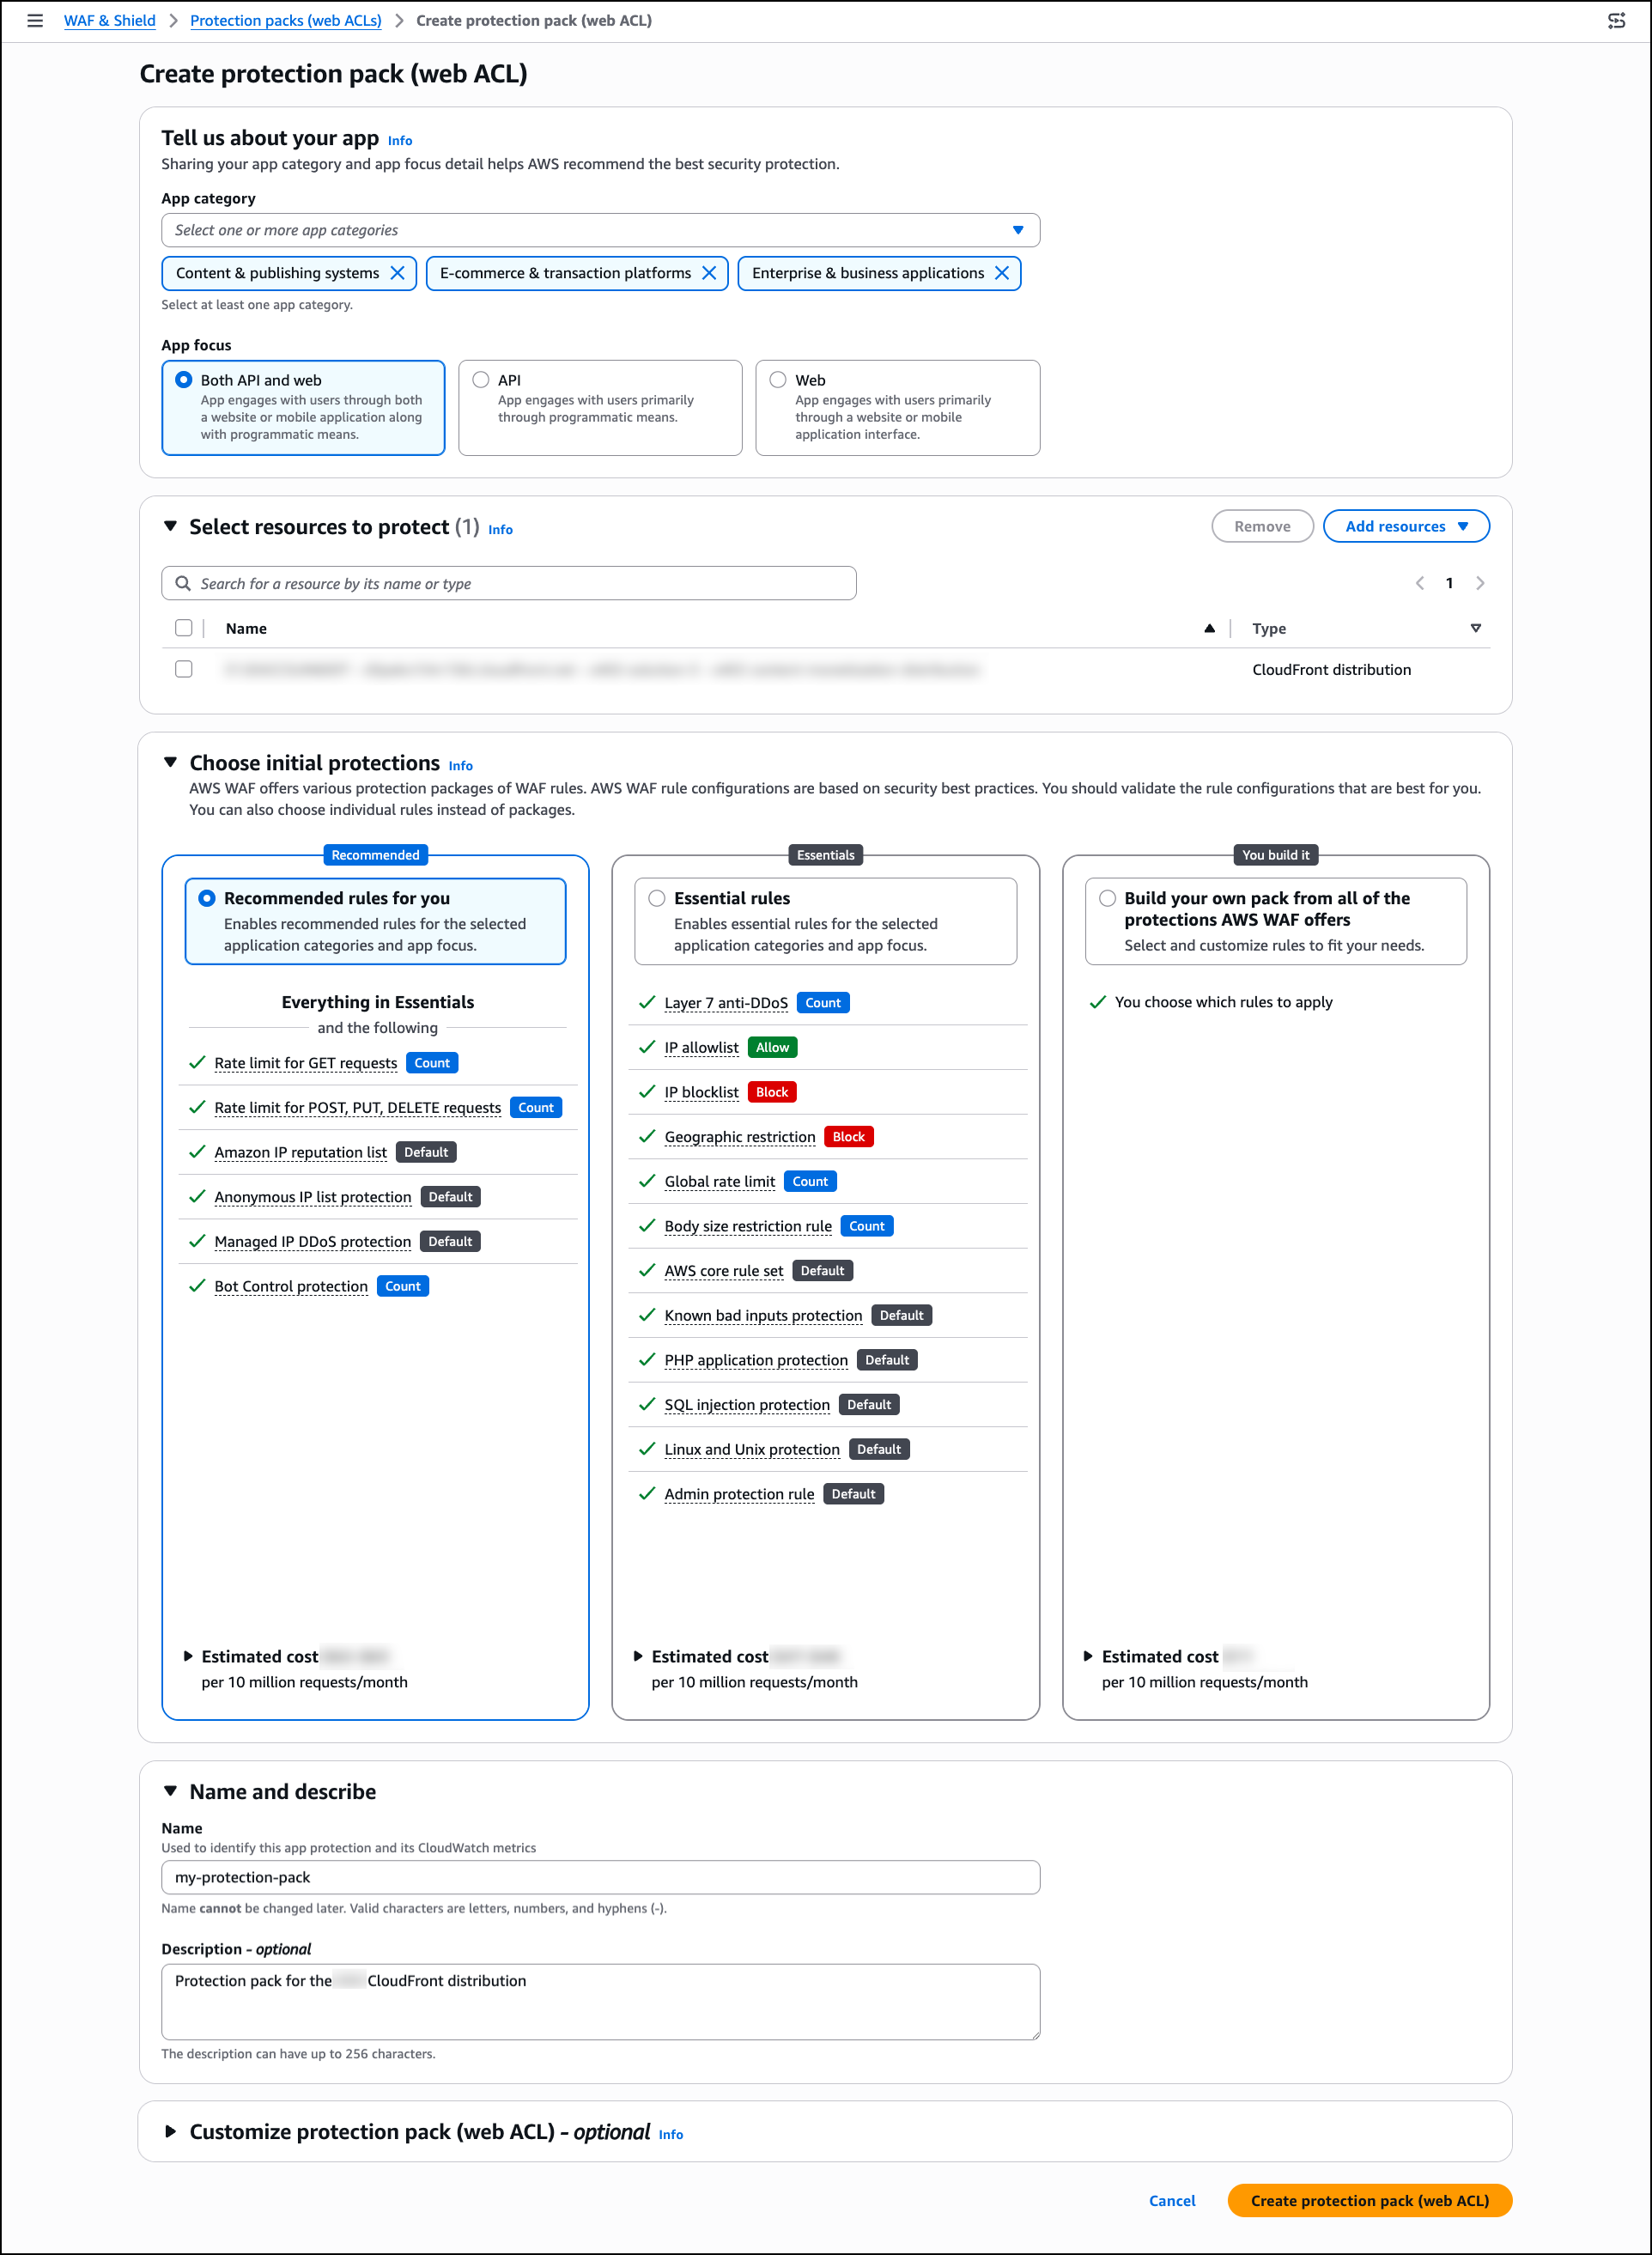
A protection pack is the core configuration unit for AI traffic monetization. It defines which content paths are monetized, what each agent verification tier is charged, which payment methods you accept, and what license terms apply. To create one, choose Create protection pack (web ACL).
In Tell us about your app, select one or more app categories that describe your content (for example, Content & publishing systems, E-commerce & transaction platforms, or Enterprise & business applications), and choose an App focus. AWS WAF uses these selections to recommend suitable security protections for your configuration.
In Select resources to protect, choose Add resources to associate regional or global resources such as CloudFront distributions with this protection pack. You can skip this step and add resources later.
In Choose initial protections, select from AWS WAF managed rule packages based on your app category and resource selections. You can also choose individual rules instead of packages.
In Name and describe, provide a name and optional description for the protection pack.
Optionally, expand Customize protection pack (web ACL) to configure additional settings including pricing tiers, payment methods, content scope, and license terms.
When finished, choose Create protection pack (web ACL).
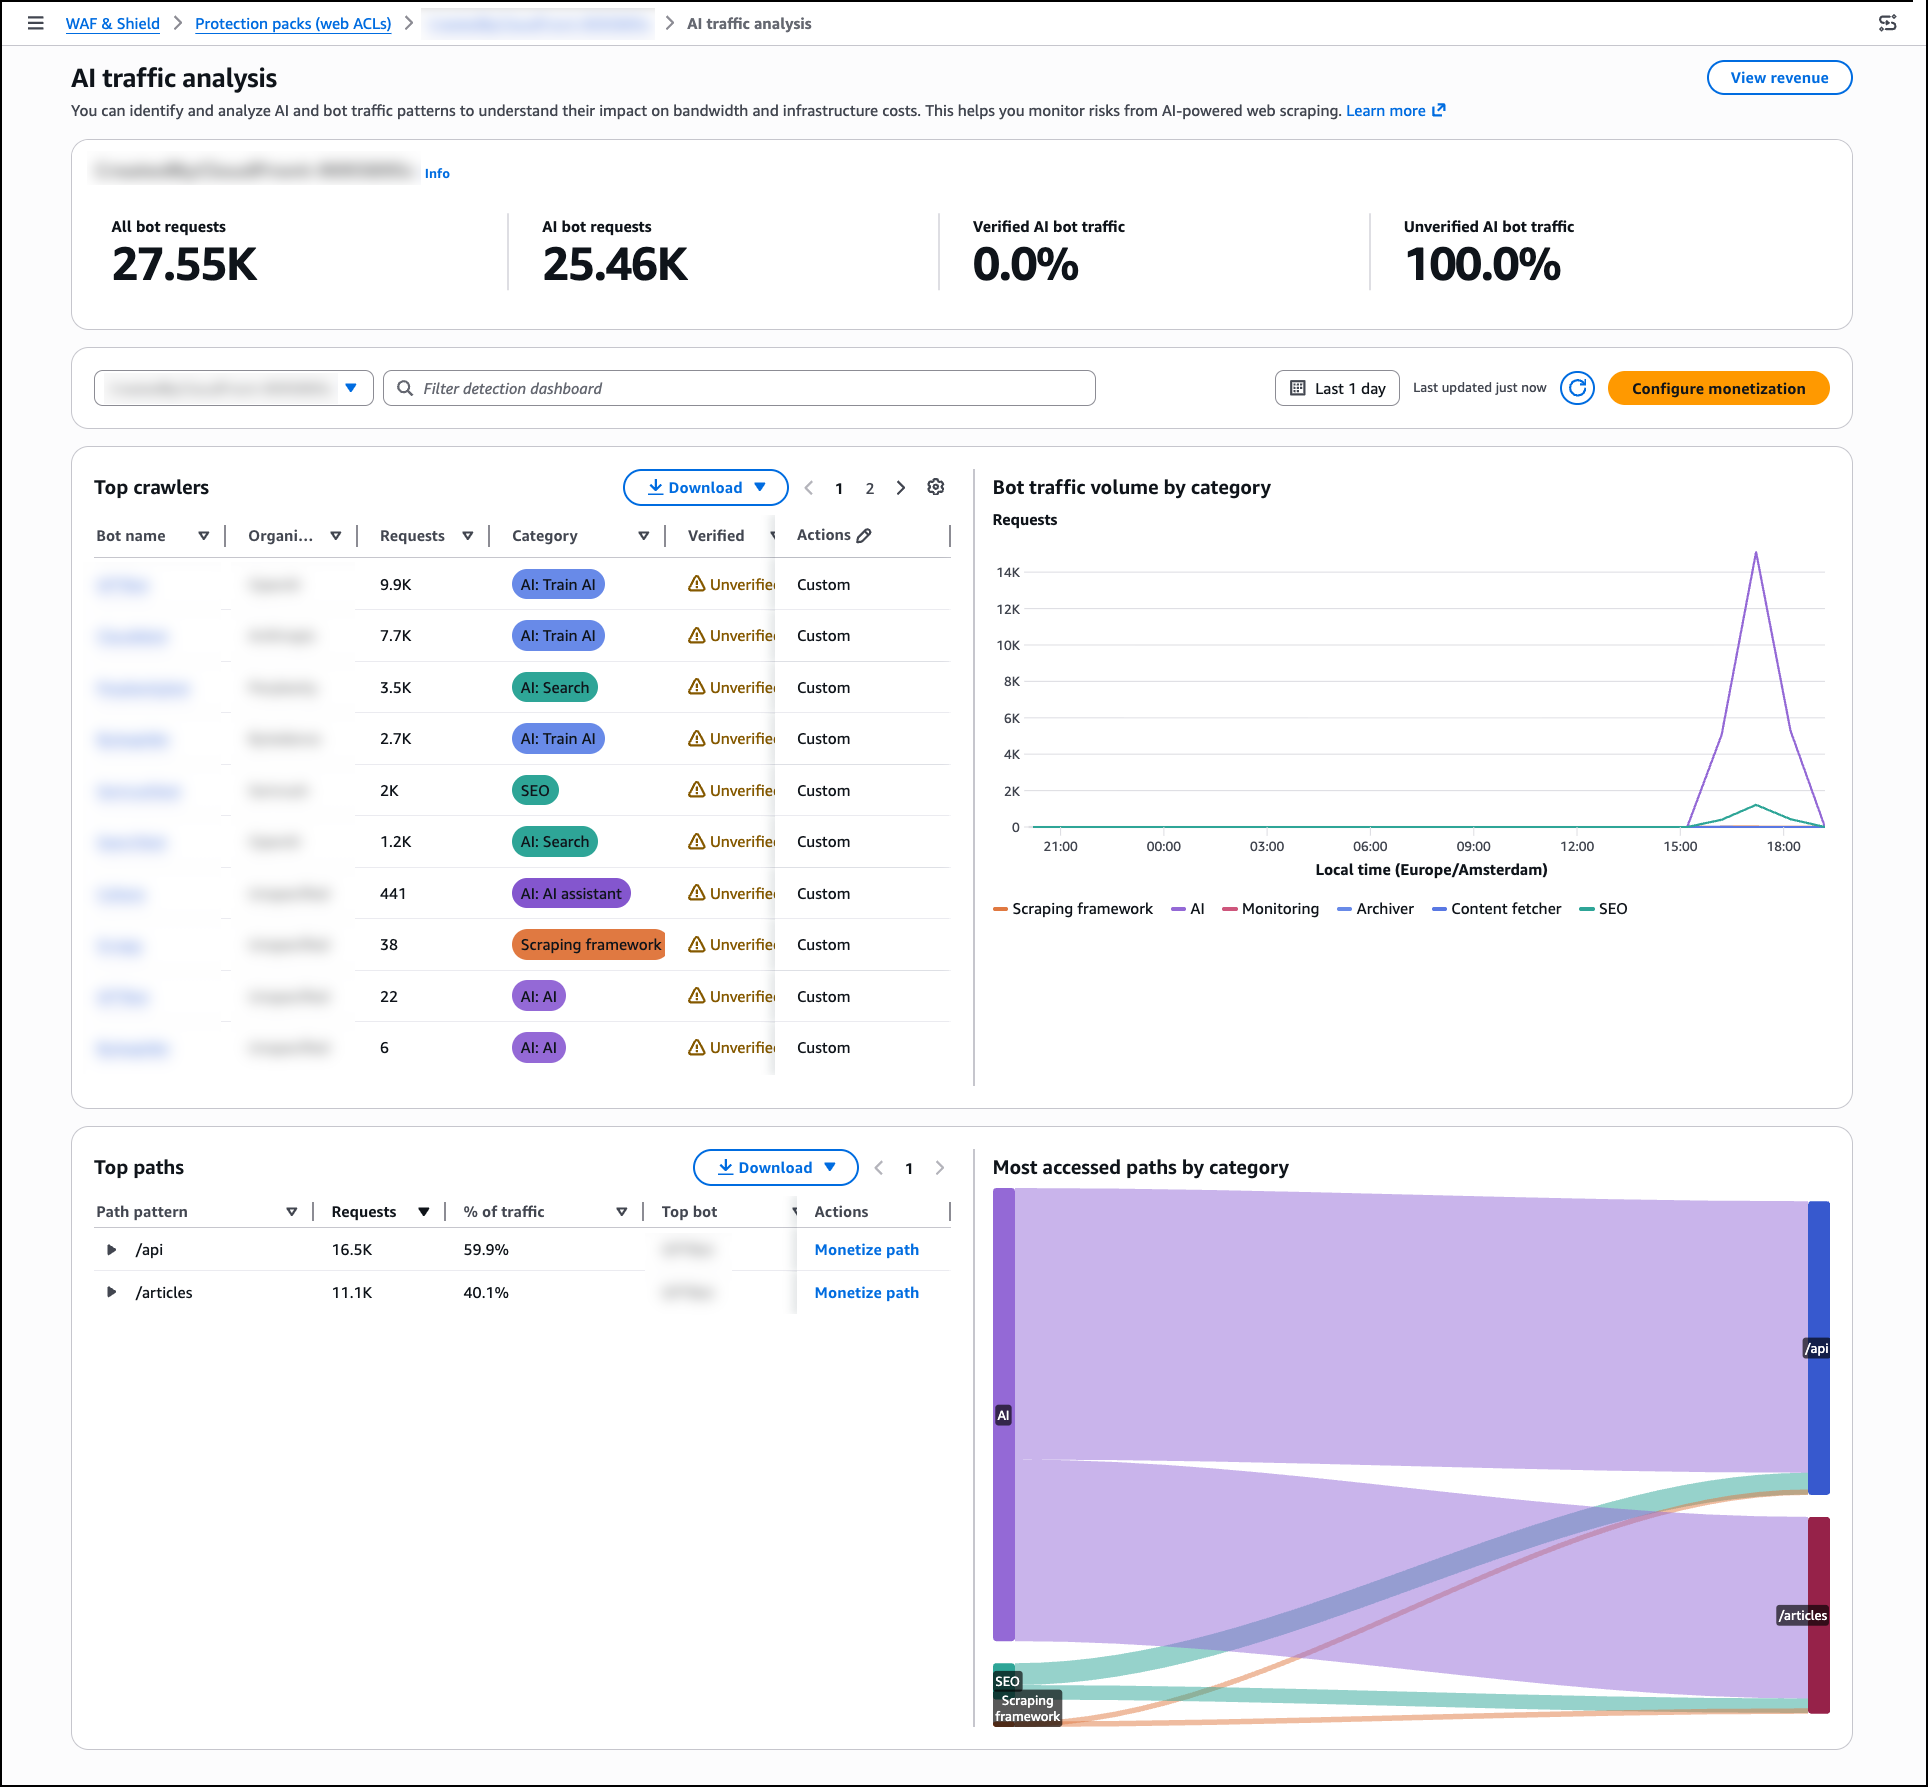
Once your protection pack is in place, review the AI traffic analysis dashboard to understand the impact of AI bot traffic on your content before setting your pricing strategy. In the WAF & Shield console, go to AI traffic analysis in the left navigation pane. Select your protection pack (web ACL) from the dropdown to populate the dashboard.
The AI traffic analysis dashboard breaks down traffic into four categories visible in the bot traffic overview panel: All bot requests, AI bot requests, Verified AI bot traffic, and Unverified AI bot traffic. The dashboard surfaces infrastructure impact metrics including bandwidth consumed, estimated monthly cost, and peak request rates. A per-path heatmap shows which content paths receive the most AI bot activity by hour, giving you the data you need to make informed pricing decisions.
AWS WAF Bot Control classifies over 650 distinct AI bot and agent types including GPTBot, Claude-Web, and Perplexity-Bot, and assigns each a verification tier:
Verified — Agent identity confirmed through Web Bot Auth (WBA) Ed25519 cryptographic signature, or sourced from a documented IP range with a known set of user-agents and domain names.
Unverified — Agent recognized through user-agent matching, behavioral fingerprinting, and IP reputation, but identity not cryptographically confirmed.
Once you have reviewed your traffic patterns, return to Protection packs (web ACLs), select your protection pack from the list, and choose Configure AI monetization from the right panel to set pricing and access policies. Each protection pack defines the pricing, agent policies, accepted payment methods, and license terms that apply to a defined set of content paths. You can create multiple protection packs and apply different pricing to different content zones within the same distribution. Once created, associate the protection pack with your web ACL by opening the web ACL and choosing Add protection pack.
For each agent verification tier within the pack, you can assign one of six actions: Monetize (return a 402 with pricing), Allow (grant free access), Block (deny access entirely), Count (log without charging), CAPTCHA (present a puzzle to verify a human sender), or Challenge (run a silent check to verify the client is a browser, not a bot).
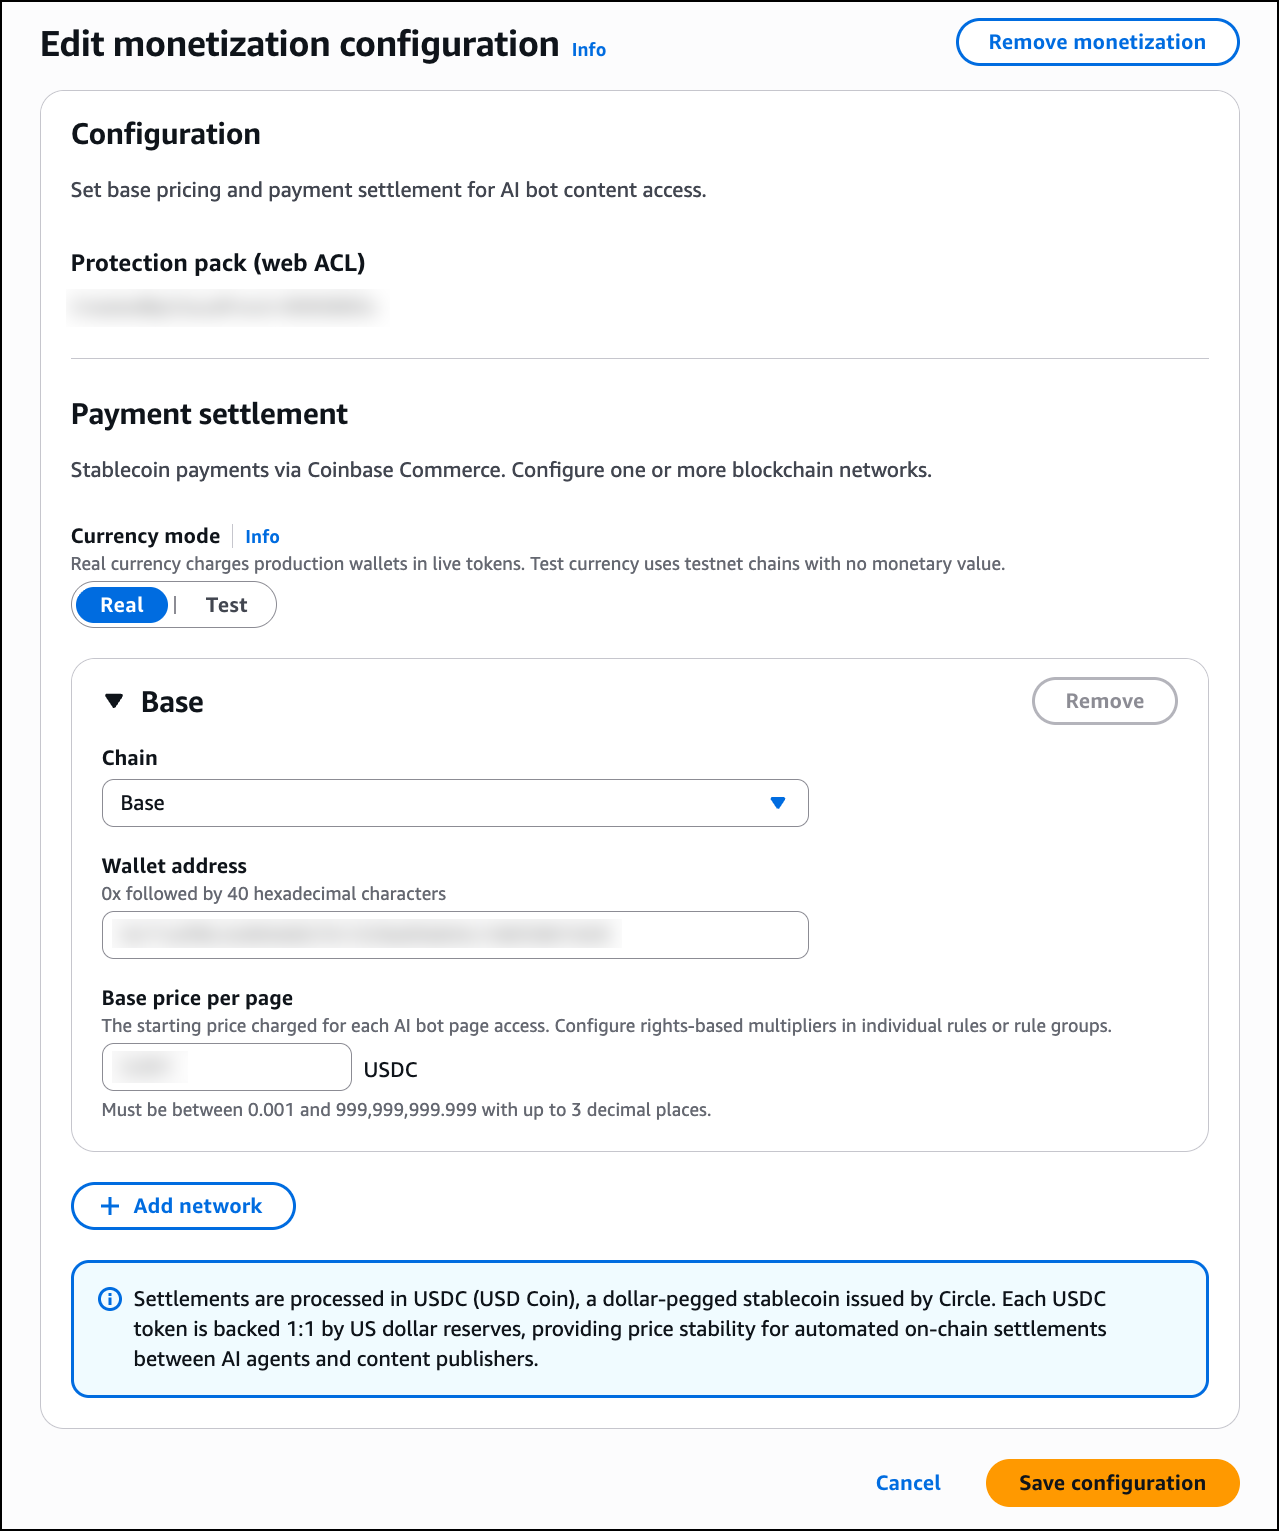
In the Edit monetization configuration page, configure the following:
Under Payment settlement, select one or more blockchain networks for stablecoin payments. Any wallet address on the supported networks is accepted, whether self-managed or hosted by a wallet provider such as Coinbase. For each network, provide your wallet address and set a Base price per page in USDC. You can add multiple networks using Add network. AWS does not process payments or take a fee on content revenue; disbursement is self-managed or managed by your wallet provider.
When a Monetize rule matches an incoming request, AWS WAF returns an HTTP 402 Payment Required response. The response body contains a machine-readable price manifest in JSON format using the x402 open protocol for machine-to-machine payments. The manifest includes the content price in USDC, accepted blockchain networks such as Base and Solana, the destination wallet address, the maximum payment timeout, and the payment scheme.
Any x402-compatible agent runtime can complete this flow autonomously. The client submits a signed payment authorization on their payment network of choice. AWS WAF verifies it, fetches the content, integrates with third-party facilitator services for settling the payment on-chain, and serves the response.
Note that the Monetize action is supported exclusively for web ACLs associated with Amazon CloudFront distributions. Adding a Monetize rule to a regional web ACL is not supported.
Since the Currency mode toggle is available directly in the monetization configuration page, you can switch between Real and Test mode at any time. Before going live, use test mode on non-production traffic to validate pricing, wallet configuration, and x402 payment flows. Note that test mode still enforces x402 payments, but those payments can be made on testnets such as Base Sepolia or Solana Devnet using test funds obtained from faucets such as faucet.circle.com. To activate test mode, toggle Currency mode to Test in your protection pack configuration. AWS WAF returns real price manifests and runs the full payment flow identically to production on the configured test chain. All events are logged with CurrencyMode: TEST. When satisfied with the configuration, toggle Currency mode back to Real to begin processing real payments.
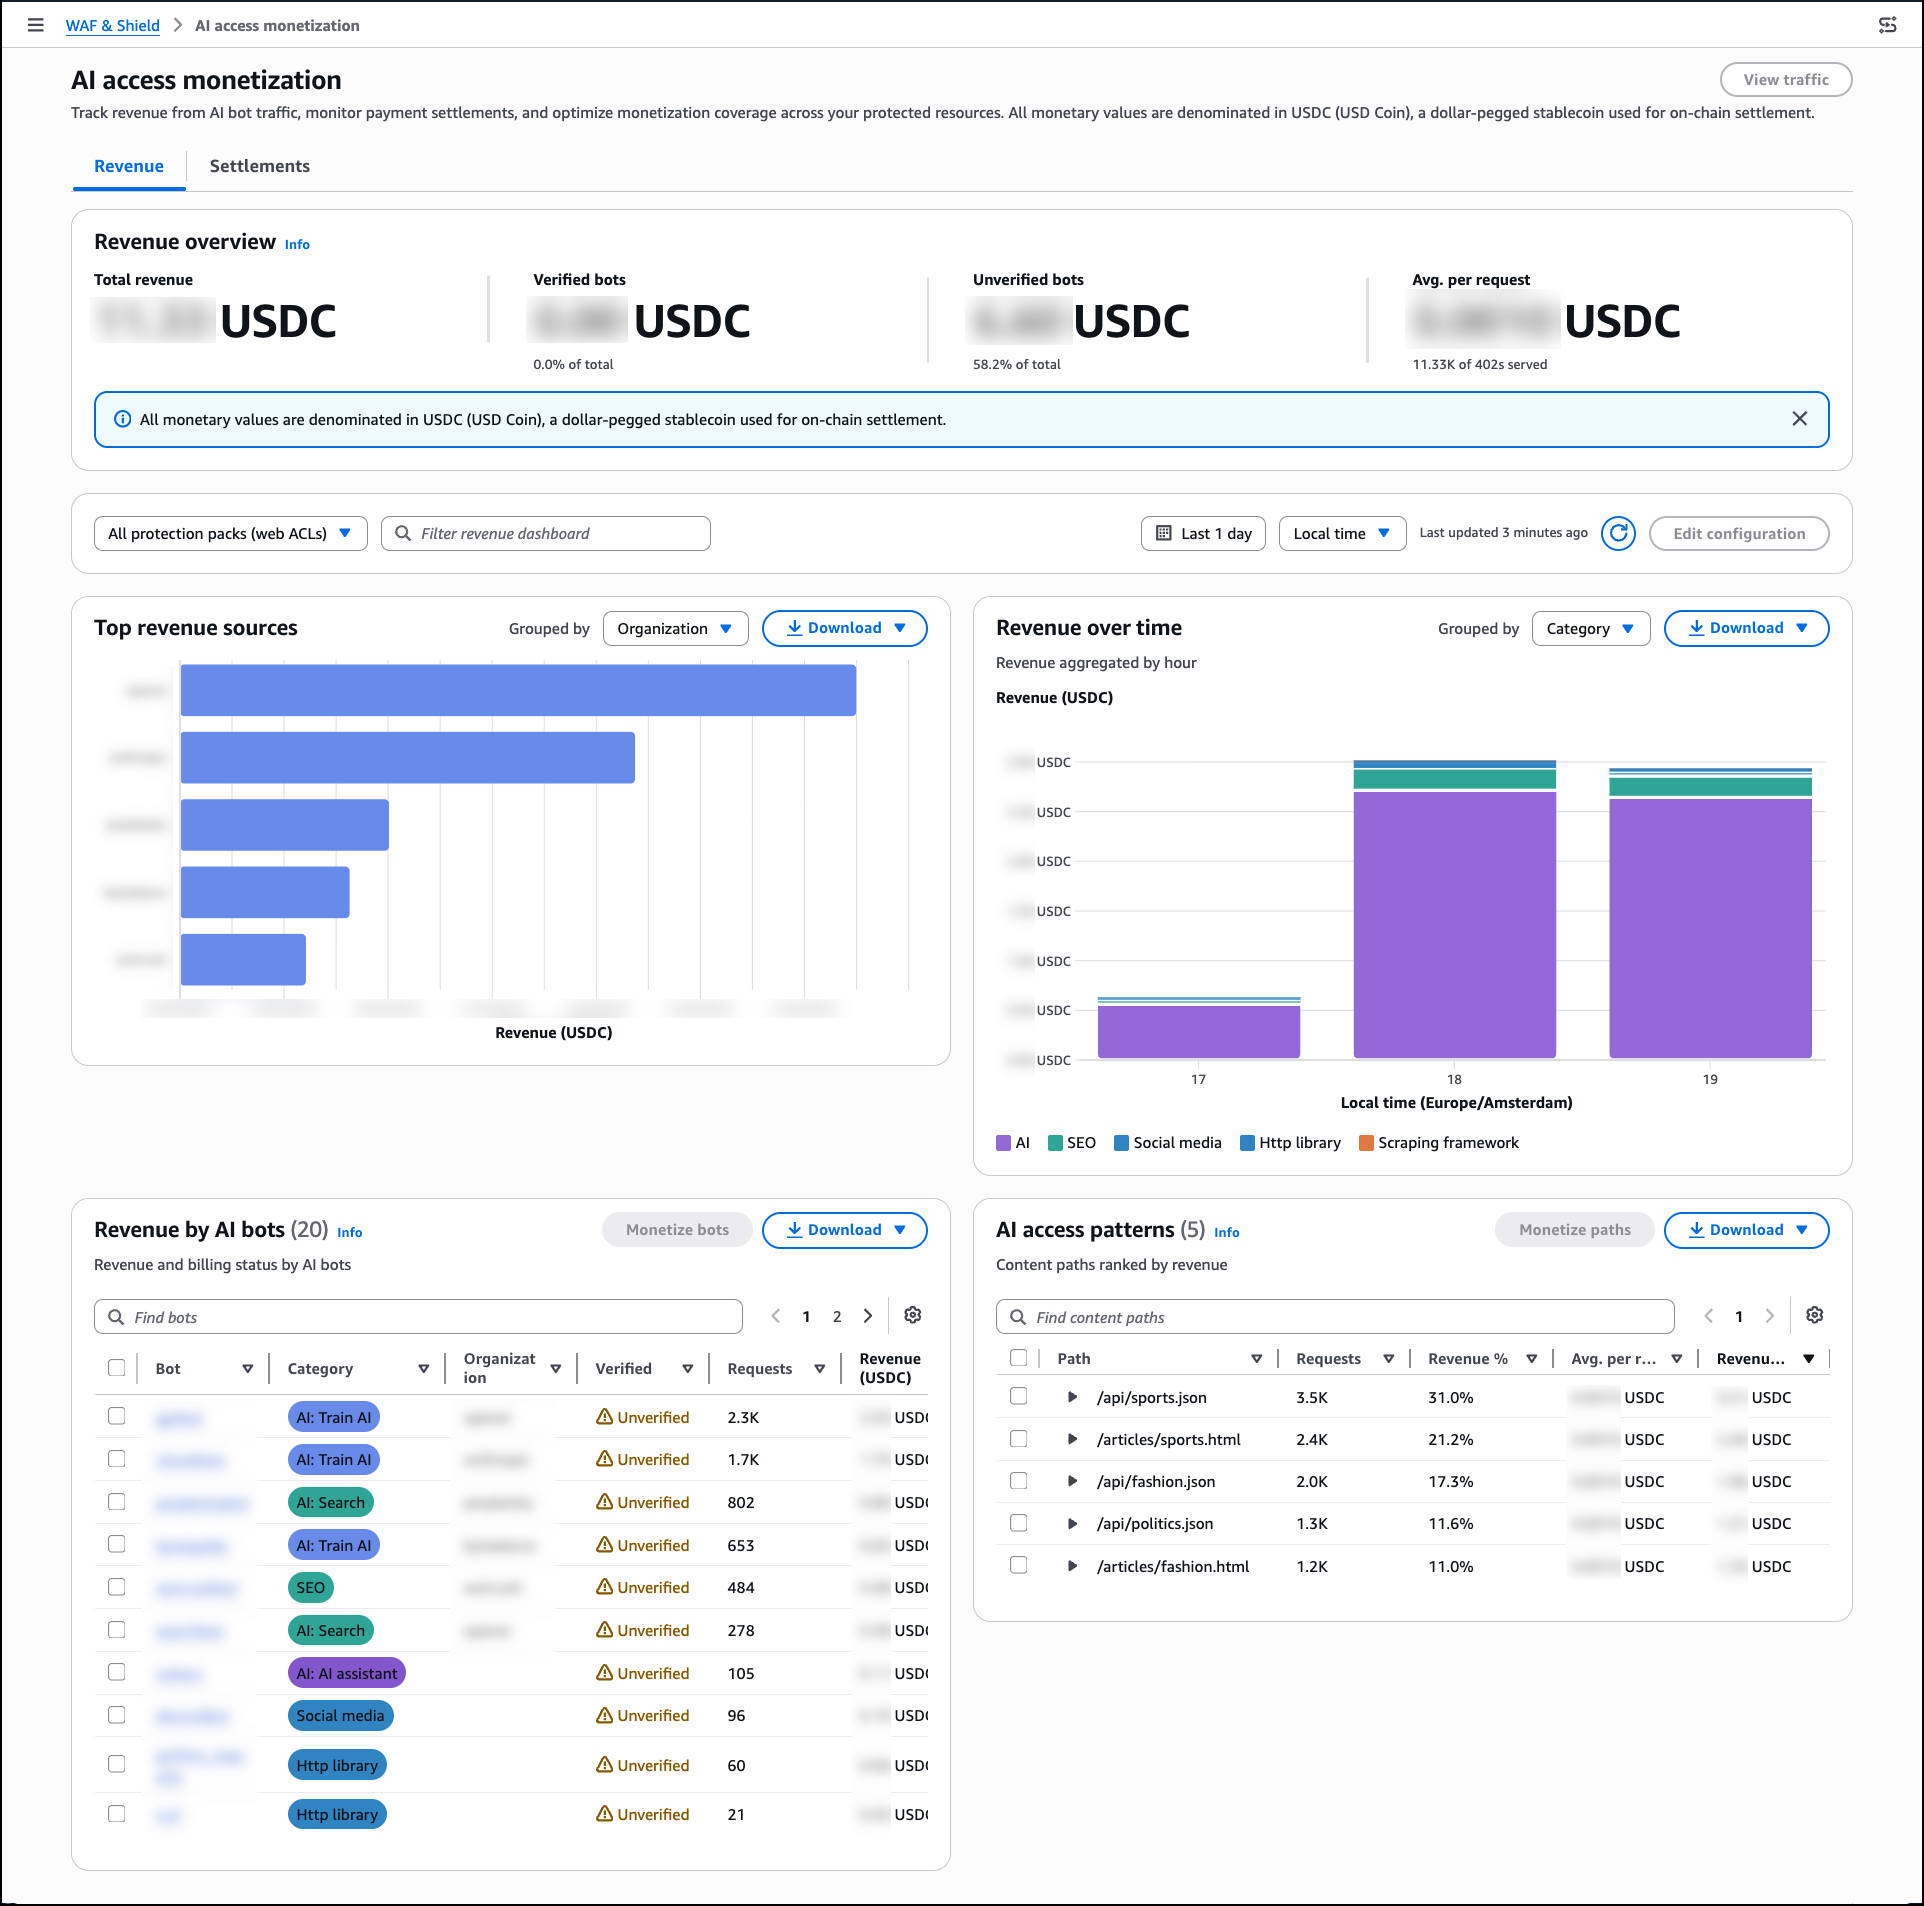
Once you have switched Currency mode to Real, navigate to AI access monetization in the left navigation pane to track monetization outcomes in real time. Note that the AI access monetization dashboard only reflects activity from real currency mode and does not display test transactions.
The Revenue dashboard shows Total revenue, revenue broken down by Verified bots and Unverified bots, and Avg. per request. The Top revenue sources panel groups earnings by bot category, and the AI access patterns panel ranks content paths by revenue generated. Use the Settlements tab to reconcile payments by provider and review payment method distribution and failed payment attempts.
Now Available AI traffic monetization is available now for Amazon CloudFront customers at no additional charge beyond standard AWS WAF pricing. The capability is available in all edge locations where AWS WAF web ACLs are associated with Amazon CloudFront distributions.
Customer records live in the database. Payment activity is safely stored in your payment processor. Call recordings and transcripts live in Zoom, Teams, Webex, or another video conferencing application–or are shared to Gong for customer insights. Telemetry resides in an observability tool like Grafana or DataDog. Your own day-to-day work is in Google Drive or OneDrive. It takes hundreds of human hours to figure out what customer behavior and business continuity patterns can be extracted from all of this data.
Extracting insights from your data starts with knowing what you have. The first step is centralizing it — pulling multimodal data from across your systems into a single storage repository where your engineering team and AI agents can actually access it. From there, you can assess what’s useful, what’s usable, and what still needs to be labeled or anonymized before it’s ready to work with.
Assessing your data is like cleaning out the garage: first, you have to do a full inventory to know what you actually have before deciding on new data destinations and purposes.
The hidden data silos most organizations overlook
One of the less-discussed barriers to AI readiness is that many organizations lack a complete picture of their own data assets.
Financial assets are documented. Physical assets are tracked. But images, audio recordings, video files, email archives, documents, logs, and customer interaction histories often sit across systems with inconsistent labeling, unclear ownership, disparate tooling, and no centralized catalog.
Customer calls, support chat transcripts, QA screen captures, surveillance footage, and product images all contain operational insight that can inform AI applications, assuming they’re stored in a way that makes them accessible and usable. Most organizations haven’t done that inventory and don’t know what data they’re sitting on.
In our experience, organizations that broaden their definition of data — and build infrastructure to collect and manage it centrally — consistently find that their AI potential is larger than they initially estimated. The inverse is also true. Organizations that skip this step tend to hit the data silo problem mid-project, when data they assumed was available turns out to be fragmented, unlabeled, or simply missing.
The term “multimodal” describes this in practice: datasets that span formats—images, audio, video, text, and structured records—within the same pipeline. Managing multimodal data at a meaningful scale requires infrastructure decisions made well before an AI project kicks off.
Where the infrastructure question meets the strategy question
Here’s what aligning AI strategy with data strategy actually requires:
Inventory what you have. Before sourcing anything new, take stock of what exists. Support call recordings, usage footage, survey data, transaction histories—these are continuously generated across most organizations and rarely treated as AI assets. A governance committee (described below) is the natural owner of this inventory.
Establish governance before you deploy. Who can use which data, under what conditions, and for what purposes. When data governance is established early, teams get answers in days rather than weeks. When it’s deferred, it becomes a bottleneck mid-project.
Plan storage infrastructure for what you will have, not just what you have. A storage decision made today carries a different cost profile 18 months from now. Hyperscaler egress fees that look manageable on a pilot-scale workload become structural constraints at training scale. Archive tiers that appear to reduce costs carry retrieval latencies incompatible with active AI pipelines. Modeling these costs before committing to a provider architecture prevents the predictable trade-offs: smaller datasets, shorter retention windows, fewer training cycles.
Make the C-suite part of the conversation. IBM’s 2025 CEO Study found that 68% of AI-first organizations have mature, well-established data and governance frameworks. When the CEO is involved in AI governance decisions, the conversation stays connected to business strategy instead of fragmenting into siloed technical decisions.
The competitive advantage lives in the data (silos)
Foundation models are increasingly commoditized. The leading model today will be superseded within months, and capable alternatives are widely available from multiple providers. The latest generation from any major provider is capable, widely available, and will be superseded by something better within months. What cannot be licensed, replicated, or accessed by a competitor is the proprietary data your organization has built up over years of operation: customer patterns, process histories, institutional knowledge.
Getting that data foundation right is what separates AI programs that scale from those that stall.
Organizations that align their AI strategy with their data strategy from the start make fundamentally different infrastructure decisions. They choose storage providers that support active data movement without penalizing it. They build governance structures that give the right people access without creating bottlenecks. And they treat data growth as a business opportunity, not a cost to manage.
For most organizations, that shift in thinking starts with a simple question: who owns AI strategy? If the answer is “it’s fragmented across different teams,” then the second question is: what would it take to bring those conversations into one room?
Everything that follows—the data readiness, the governance, the infrastructure that actually works at scale—flows from that first alignment.
The NIS2 directive asks covered organizations to take a more structured approach to risk management, governance, supply chain security, and incident reporting. It expands the scope of who may be covered, raises expectations around management body accountability, introduces clearer and more enforceable requirements, and increases pressure on organizations to show that security is being managed in a consistent, defensible way. Reporting timelines are one of the most visible parts of that shift, with early warning required within 24 hours of awareness for significant incidents, incident notification within 72 hours, and a final report within one month. It also arrived in a landscape that is still uneven, with member states continuing to implement the directive in different ways across the EU.
That combination has created a familiar challenge for CISOs and security teams, as the questions coming from boards and leadership are no longer just about whether the organization understands the regulation, but whether it can meet the requirements in practice. NIS2 reaches into risk management, reporting, governance, and supply chain oversight, which means readiness depends on how well security works across the business, not just on how well a policy is written.
That is why the most useful way to think about NIS2 is as an operational resilience exercise. Compliance still matters, of course, and teams need to know what the directive requires. What tends to make the difference over time is whether security leaders can connect those requirements to the real conditions of the environment: what is exposed, where ownership sits, how incident response works in practice, how supply chain risk is monitored, and how quickly the organization can move when something material happens.
Regulations are easier to absorb than operating model changes. A team may understand that NIS2 raises expectations around governance and incident handling, while still finding it difficult to answer basic questions quickly when pressure rises. Which business services are most critical? Which third parties matter most? Who owns the decision when a serious issue lands? How prepared are we to investigate, communicate, and report inside the timelines the directive expects? Those are the questions that separate a compliance project from a resilience program.
That is also why we have been building practical content to help teams move from interpretation to action.
Our ebook is the best place to start if you want the wider context. It is designed to help security leaders understand what NIS2 means in practical terms, how to think about the directive beyond a narrow checklist, and how to connect compliance obligations to a broader resilience strategy. If your team needs a stronger narrative for internal stakeholders, or a clearer way to explain why NIS2 should influence operational priorities, the ebook is the most useful first read.
Next, our NIS2 Readiness Toolkit is built for teams that want to assess where they are and what to do next. iIt is as a way to bridge the gap between NIS2 requirements and operational reality, with a focus on risk, reporting, and governance. It is designed to help teams spot gaps, focus effort, and simplify the path from regulatory complexity to a more defensible security strategy. In other words, it gives you a practical framework for understanding where readiness is strong, where it is uneven, and what deserves attention first.
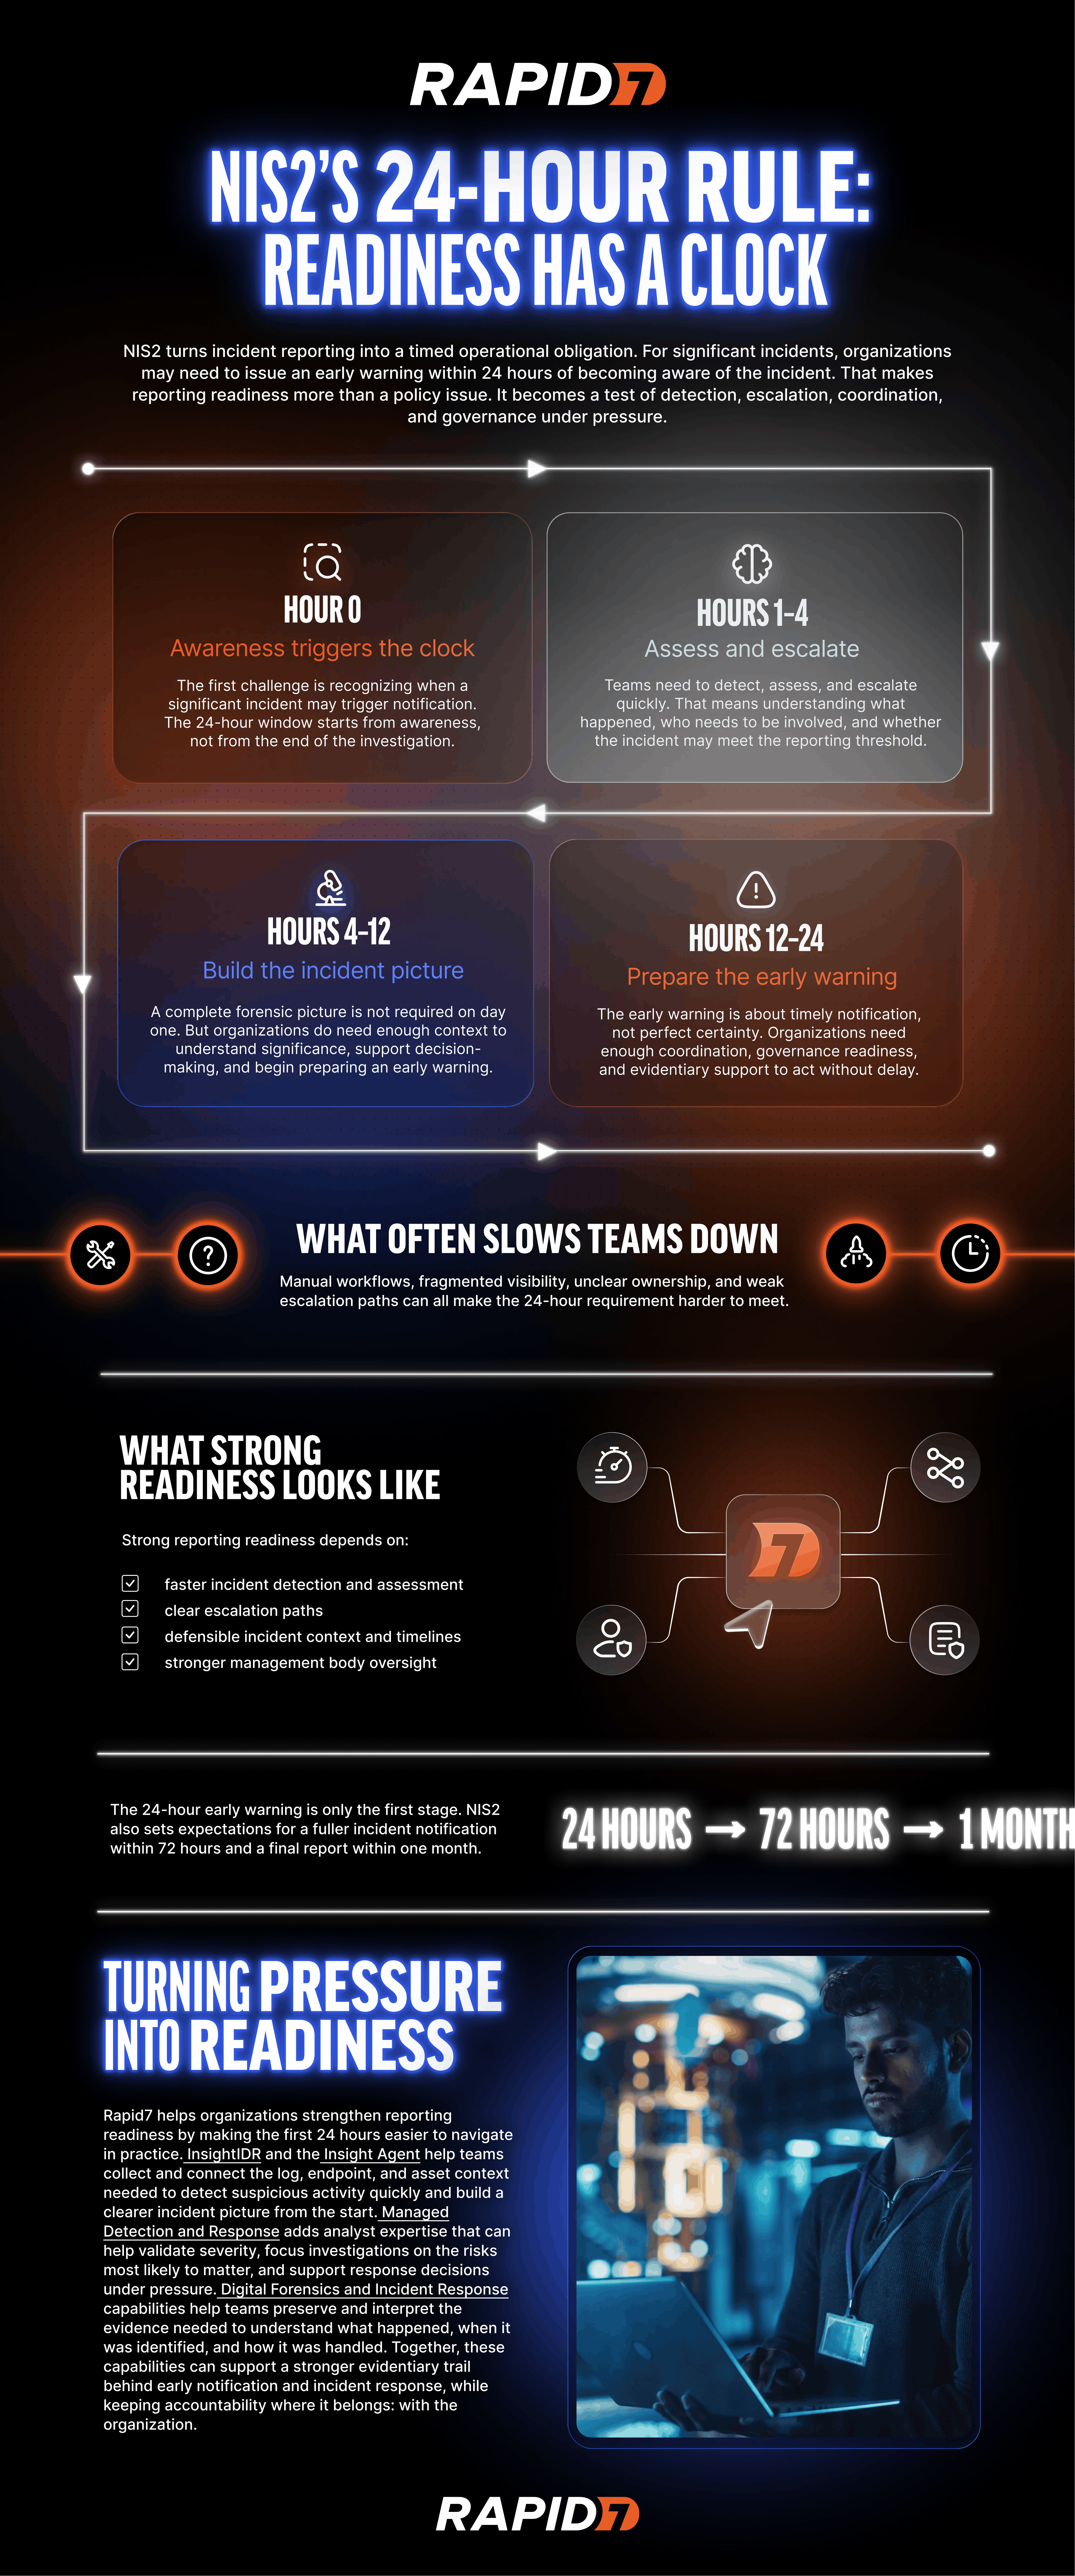
Our infographic, seen below, is the quickest asset to use when you need to communicate one of the most tangible parts of NIS2: the 24-hour reporting requirement. Some stakeholders need the long-form explanation. Others need a practical view of what has to happen between incident awareness and early notification. The infographic helps teams bring that operational pressure into planning conversations, leadership updates, and internal alignment without requiring everyone to start with a longer asset first.
⠀
Taken together, these assets are useful because they serve different parts of the same problem. The ebook gives you a strategic view, the toolkit helps you assess readiness and prioritize action, and the infographic helps communicate the big picture quickly and clearly.
Enforcement expectations, reporting maturity, and national interpretation continue to evolve, and security teams are working through those changes at the same time as the wider threat landscape becomes more complex. A stronger response starts with clarity, but it needs to move quickly into coordination, ownership, and repeatable process if it is going to hold up under pressure.
If your organization is still treating NIS2 as a point-in-time compliance exercise, now is a good moment to widen the lens. The directive is pushing security leaders beyond a comply-once approach and toward a model of being continuously secure. Teams that build better visibility, stronger governance, and clearer response processes for NIS2 will be better prepared not only for regulatory scrutiny, but for the wider operational demands that are already shaping the market.
If your organization operates in the EU, or works with organizations that do, NIS2 is no longer something on the horizon. It is here and it applies to a far wider range of sectors than its predecessor, the original NIS Directive (Directive (EU) 2016/1148), and it comes with real consequences for organizations that cannot demonstrate they are meeting its requirements. The good news? You do not have to figure out how to approach it alone.
Rapid7 has developed a dedicated NIS2 resource page that shows how the Command Platform can support key technical and operational aspects of NIS2 readiness, highlights common security program gaps, and explains where our solutions can help strengthen visibility, prioritization, detection, and reporting readiness. It is not a substitute for the broader organizational, legal, and governance measures the directive also requires, but it can be a useful starting point if you are evaluating your security capabilities and want a clearer picture of where tooling can support your approach. If you are in the early stages of assessing readiness, or further along and looking for a clearer view of the technical side, it is worth 10 minutes of your time.
What are the NIS2 requirements organizations need to meet?
NIS2, formally Directive (EU) 2022/2555, expands the scope of EU cybersecurity regulation significantly. More sectors are covered,the requirements are more demanding, and, crucially, the expectations have shifted from “do you have policies in place?” to “can you demonstrate that your controls actually work, continuously?”.
Article 21 mandates specific risk-management measures, including risk analysis, incident handling, business continuity, supply chain security, vulnerability handling, access control, and policies regarding the use of cryptography and encryption.. Article 23 introduces strict incident reporting timelines: an early warning within 24 hours, a full notification within 72 hours, and a detailed report within one month of a significant incident.
For many security teams, these timelines necessitate a shift in operational readiness. Timely and accurate incident reporting requires pre-established detection workflows, investigation processes, and contemporaneous documentation practices to be in place prior to an incident..
NIS2 also raises the stakes at a leadership level. Executive accountability for cybersecurity is now formalised. This is not just a technical team problem. It is a governance issue that touches CISOs, boards, and senior leadership across every in-scope organization.
Why traditional compliance approaches fall short of NIS2
Many security programs were designed around a different set of expectations. Periodic vulnerability scans.,annual audits, and compliance reports that reflected a moment in time rather than ongoing operational health.
NIS2 necessitates a move toward continuous, defensible risk management. This involves maintaining comprehensive asset visibility, identifying threat-aware exposures with high likelihood of exploitability, and validating the effectiveness of detection capabilities to support regulatory reporting requirements..
It is a meaningful operational shift, and it is exactly the kind of shift where having the right platform and the right partner matters.
How does Rapid7 support NIS2 compliance?
Rapid7 views NIS2 as an operational readiness challenge. The objective is to assist organizations in transitioning from periodic compliance assessments to continuous resilience: a sustained, measurable security posture designed to support regulatory alignment and strengthen defense-in-depth against emerging threats. The platform integrates exposure management, vulnerability management, cloud security, SIEM, and managed detection and response to provide broad support for the core requirements of Article 21 within a unified, connected view of risk..
That means organizations can move from scattered, point-in-time security activity to continuous visibility, threat-informed prioritization, faster incident workflows, and the kind of evidence and reporting that NIS2 and regulators actually demand.
A few areas where this makes a real difference:
Knowing what you are actually exposed to
Rapid7 is positioned as a Leader in the 2025 Gartner® Magic Quadrant™ for Exposure Assessment Platforms, a technology category fundamental to the Continuous Threat Exposure Management (CTEM) framework, which supports the proactive risk-management objectives of NIS2. Surface Command provides centralized visibility across internal and external environments, supporting the identification of unmanaged assets, shadow IT, and security control gaps that may otherwise remain undetected. Exposure Command utilizes active risk scoring and attack path analysis to identify and prioritize exposures based on reachability and threat context, helping teams focus remediation efforts on high-impact risks.
Responding and reporting faster
Rapid7’s SIEM and MDR capabilities are designed to support the detection, investigation, and reporting speed necessitated by NIS2. 24/7 monitoring and managed response facilitate the capture of essential telemetry and investigation trails within the SIEM, streamlining the evidence collection process for regulatory reporting.
Demonstrating that controls work
NIS2 is not satisfied by a list of tools you have purchased. It wants evidence that your controls are effective. Rapid7 provides continuous risk scoring, detection metrics, and audit-ready reporting that translates security activity into governance-ready language for leadership and regulators.
Where to go next for NIS2 readiness
This post covers the highlights, but Rapid7’s NIS2 resource page goes much deeper.
It walks through each of Article 21’s requirements in plain language, maps them to specific Rapid7 capabilities, and shows how the platform supports risk analysis… MFA monitoring, and technical assessment of cryptographic configurations. Whether you are a CISO seeking a strategic overview, a security manager evaluating technical controls, or a compliance lead mapping regulatory requirements to platform capabilities, our guidance is designed to support your objectives. NIS2 is operational; your approach to resilience should be as well. NIS2 is operational and your readiness should be too.
Linus Torvalds released
the 7.1 kernel as expected on June 14. This development cycle
brought in a lot of new features — and a lot of new developers as well.
The time has come for our traditional look at where the changes in 7.1 came
from, with a digression into how our community may be changing in general.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.