Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=lEdYuzLq-WA
Another batch of single-fix stable kernels
Post Syndicated from jzb original https://lwn.net/Articles/1086226/
Greg Kroah-Hartman has announced the release of the 6.18.41, 6.12.100, 6.6.147, 6.1.180, 5.15.213, and 5.10.262 stable kernels.
Each of these kernels contains a single fix for a use-after-free
vulnerability (CVE-2026-64560). Users
of these kernels are advised to upgrade.
Security updates for Thursday
Post Syndicated from jzb original https://lwn.net/Articles/1086225/
Security updates have been issued by AlmaLinux (gstreamer1-plugins-bad-free, libtiff, libXfont2, nodejs:22, nodejs:24, and rest), Debian (expat and nss), Fedora (libssh, nginx, nginx-mod-brotli, nginx-mod-fancyindex, nginx-mod-headers-more, nginx-mod-modsecurity, nginx-mod-naxsi, nginx-mod-vts, nodejs24, perl-HTTP-Date, proftpd, squid, unbound, and wordpress), Oracle (c-ares, edk2, freerdp, go-fdo-server, libreswan, mariadb-connector-c, and nginx), SUSE (alloy, apache-commons-lang3, google-guice, maven, maven-resolver, xmvn, apache-sshd, apptainer, avahi, distribution, glib2, go1.26-openssl, go1.25-openssl, go1.24-openssl, go1.23-openssl, go1.22-openssl, go1.26, go1.25, go1.24, go1.23, go1.22, go1.21, gstreamer-plugins-bad, helm, ImageMagick, java-17-openjdk, java-25-openjdk, liboqs, oqs-provider, libssh, nginx, nm-configurator, nmap, openssl-3, openvpn, PackageKit, perl, perl-DBI, perl-HTTP-Date, perl-XML-Bare, python-msgpack-python, python-sh, python-ujson, python-urllib3, runc, samba, sssd, wget, wpa_supplicant, and xen), and Ubuntu (linux-nvidia, linux-nvidia-7.0 and linux-nvidia-6.17).
Dogfooding at scale: migrating cdnjs to Cloudflare’s Developer Platform
Post Syndicated from Simona Badoiu original https://blog.cloudflare.com/cdnjs-dev-platform-migration/
As of June 23, 2026, cdnjs, one of the Internet's busiest open-source CDNs, is running exclusively on Cloudflare’s Developer Platform. Along the way, cdnjs surfaced limits in the platform, and the platform grew to meet them.
cdnjs is a free, open-source content delivery network for JavaScript and CSS libraries. Instead of using a bundler or self-hosting jQuery, Bootstrap, or Lodash, you drop a <script> tag pointing to cdnjs.cloudflare.com and the library loads from Cloudflare's edge, instantly, anywhere in the world, with no signup, no API keys, and no rate limits. It's the infrastructure behind a significant portion of “intro to JavaScript” tutorials, CodePen demos, and Stack Overflow answers.
Community-driven, cdnjs is used on roughly 12% of all websites, a 48.3% share of the JavaScript CDN market. It serves an average of 108,000 requests per second, 9 billion per day, across more than 330 Cloudflare data centers, with a 98.6% cache hit rate. Pretty cool, Internet!
In 2011, when bundlers were exotic, npm was barely a year old, and "just drop a <script> tag" was how the web shipped JavaScript, Ryan Kirkman and Thomas Davis built cdnjs as a free, community-run mirror of every popular open-source library.
Cloudflare stepped in to host it free of charge months later, and took over project maintenance in 2019. Back then, Cloudflare didn't have a mature Developer Platform that could fully sustain the entire cdnjs ecosystem. Fifteen years and a lot of building blocks later, the platform is mature enough to run cdnjs end to end, on Workers, Workflows, D1, Queues, Workers Cache, R2, KV, and Containers.
Why cdnjs has 9 billion requests a day
The web has changed beyond recognition from those days. We have ES Modules (ESM), the standardized import / export syntax browsers understand natively. We have import maps, Vite, Bun, Turbopack. We have AI assistants that scaffold entire apps in seconds. Bundlers are everywhere. So why does a CDN for <script> tags still serve 9 billion requests a day?
One reason: LLMs love cdnjs. When ChatGPT, Claude, or Cursor scaffold a quick HTML demo, they reach for cdnjs because their training data is full of it. There have been 15 years of blog posts, GitHub READMEs, tutorial sites, and Q&A threads pointing to cdnjs.cloudflare.com. The URL pattern is consistent and versions are immutable — exactly the kind of dependency a model can produce reliably without hallucinating.
Every file on cdnjs has an SRI hash (we're still working on ensuring all the existing stored hashes match reality due to bugs in the old system), mirrors are auditable, and the whole project is open source. In a world increasingly worried about supply-chain attacks, an immutable, hash-verified mirror of well-known libraries is indispensable.
And it's free, forever, for everyone. No API keys. No rate limits. No "sign up to continue." That's a rare thing on today's Internet, and it's worth protecting.
Why we migrated
We didn't migrate because cdnjs was slow. We migrated because we want to keep improving it.
The previous architecture served users well: 98% cache hit, billions of requests, no outages. But internally, shipping anything new or fixing existing issues in how packages were processed was getting harder. Making a change meant coordinating deployments across GCP Functions, a VM, and Cloudflare. Observability was painful too.
The pain points
In 2020, we migrated cdnjs to serverless, moving file serving onto Cloudflare Workers and KV, with a bare-metal origin as fallback. That change dramatically improved resilience and scalability, and let us pre-compress every asset with Brotli and gzip for smaller, faster responses, but only on the serving side.
The publishing side — the pipeline that watches npm and GitHub for new library versions, downloads them, processes them, and writes the results so cdnjs can serve them — stayed on Google Cloud Platform (GCP). At the time, Cloudflare Workers were designed for fast, short-lived HTTP requests; they didn't yet have the building blocks for a long-running, multi-step pipeline that fetches large tarballs, runs CPU-heavy compression, and orchestrates work over hours. Workflows, Queues, Durable Objects, R2, and Containers didn't exist yet.
So we built the publishing bot on what was available: a chain of GCP Functions, a VM running git-sync, and a GitHub repository as the source of truth. It worked, but six years later, that architecture was showing its age. Here's a diagram of the previous architecture:
The architecture had five pain points. The one that hurt most was observability: debugging meant stitching logs together by hand. We'll start there.
- No shared trace
A single package update could pass through Cloud Functions, Google Cloud Storage (GCS) object events, Pub/Sub topics, a git-sync VM, and Workers KV before a file reached a user. None of those systems shared a correlation ID. GCP Logging held one half of the story, Cloudflare Logpush held the other, and the two had no common key to join on.The problem wasn't outright failure, it was partial success. A version that processed cleanly, wrote to KV, and then silently failed to land in the GitHub repo would serve fine for weeks until someone noticed the two stores had diverged. There was no alert for that. There couldn't be, because nothing in the system knew the full pipeline state.
- Split-brain storage
Files lived in two places at once: Workers KV at the edge (with a bare-metal origin as fallback) and a GitHub repository as the source of truth. The ingestion pipeline wrote to both at the end of every run. Neither was authoritative, and when they drifted, there was no clean way to reconcile them. - Pipeline glued together with object events
The ingestion pipeline was a chain of small GCP Cloud Functions, each doing one step and handing off to the next through shared storage. One function fetched the package's release archive from npm and dropped it in a bucket. The bucket firing a "new file" event triggered the next function, which unpacked it and wrote the results somewhere else, triggering the next, and so on. Storage was doing double duty as a message queue, with no dead-letter queue, no backlog visibility, and no clean replay when a step failed. - 26 functions for 26 letters
Just checking npm for updates required 26 Cloud Functions, one per letter of the alphabet. Each shard had its own deployment and its own logs, and the only way to know if the fleet was healthy was to check all 26. - The GitHub repo GitHub couldn't serve
A separate VM ran git-sync, mirroring every processed file into cdnjs/cdnjs. Years of releases pushed it past 1.1TB of packed storage, large enough that GitHub's own archive service refused to generate tarballs or zip downloads for it. Forking became impractical, clones were slow, and the .gitignore had grown to 274 hand-curated entries blocking broken or weirdly-versioned releases. It was a documented graveyard of everything the pipeline couldn't reasonably reject upstream.A genuine thank you to the GitHub team for hosting this giant for over a decade. They bore with us through years of storage growth, and the project wouldn't have survived without them.
A quieter benefit that came with the migration is having fewer moving parts to secure. Cloud Functions, a git-sync VM, container images, GCS buckets, service-account keys — every one of those was a thing to secure, patch, and audit. Retiring the pipeline closed all of the recently opened cdnjs vulnerabilities.
How we re-built it
The new cdnjs architecture runs entirely on Cloudflare’s Developer Platform.
R2 is the single source of truth for file content. It has no practical size limit, so the files that couldn't fit in KV before, like source maps, big bundles, and font packs, now live alongside everything else. As a bonus, the S3 API makes the entire cdnjs catalog accessible to any S3 client. Maintain a mirror? Open an issue on the cdnjs repository and we'll set you up with read-only credentials.
KV stores only metadata now: package info, version lists, SRI hashes. KV is built for high read volume with infrequent writes, which is exactly the shape of metadata access.
In front of the Worker sits Workers Cache, a tiered cache Cloudflare launched this year. Before, we relied on a separate internal caching layer between the edge and the Worker. That layer is gone now, replaced by one owned by the Developer Platform, the same platform that runs the rest of cdnjs. One less moving part!
The new architecture also extends a long-standing partnership. DigitalOcean has hosted the cdnjs website for years as a sponsor; now it hosts the storage too. Every file published to R2 is mirrored to DigitalOcean Spaces: architecturally a disaster-recovery copy, operationally also a live fallback. The serving worker reads through to it whenever R2 can’t return a file. The chain is cache → R2 → DigitalOcean, so R2 having a bad day doesn't take cdnjs down. A Cloudflare-hosted origin still sits in the chain during the transition, but it will retire once the GitHub backfill lands in R2.
The ingestion pipeline is built on Cloudflare Workflows. Every ten minutes, a cron job triggers PackageUpdatesWorkflow, which checks npm and GitHub for new versions. For each new version found, it spawns a DownloadPackageWorkflow that fetches the tarball into R2, then a ProcessingWorkflow per file that extracts, minifies, and compresses. Finally, PublishingWorkflow writes the results to R2 and KV and updates the Algolia search index.
Because Workflows provides durable execution, the state of each step is preserved. If anything fails — a network timeout, a compression error — the workflow resumes from the last successful step.
The trickier piece is how we glue Workflows to the external compression container. We pre-compress text-based files to streamline the delivery process. But compression is too CPU-intensive for a Worker, so we hand it off to Cloudflare Containers, wait for compression to complete, and then pick up where we left off.
The pipeline has two kinds of waiting:
Per file: Each ProcessingWorkflow writes the uncompressed file to an R2 bucket, sends a job to a Queue, and hibernates. A Rust compression service running in the container picks it up, compresses it, and writes the result to another bucket. An R2 event notification wakes the workflow up so it can continue.
Per package: The parent workflow needs to wait for all its file children before moving on to publish. A package with thousands of files means thousands of children running in parallel. We use a small Durable Object as a counter: a parent increments on each child it spawns, children decrement when they finish. The parent wakes up when the counter reaches zero.
An overview of the new architecture, with R2 as the source of truth and Workflows running the pipeline:
Pushing the limits
Designing the new architecture was one challenge. Migrating the existing catalog into it, without disturbing a single file already in the wild, was another.
We'd actually tried this once before and had to roll back. The plan, back then, was to re-process old packages and write the results directly to R2, but the regenerated files didn't byte-match what KV had been serving. Minifiers and compressors aren't fully deterministic across versions, so the new outputs were correct but had different SRI hashes. For a CDN where users pin those hashes in their HTML, that's a serving break. So we rolled back, and now, we migrated the existing content from KV to R2 as-is instead of regenerating it.
That decision shifted the problem from "re-process millions of files" to "copy millions of files between accounts, without missing any." And that's where we ran into the Workers subrequest limit, capped at 1,000 per invocation on paid plans. A package with thousands of files would burn through it in one go. Parallelizing didn't help, since every Worker hits the same ceiling. So we sharded the migration by package name and fanned the work out across many invocations via Queues, whose at-least-once delivery guarantee meant no package could silently fall out of the migration.
We hit two platform limits during the migration: 1,000 subrequests per Worker invocation and 1,024 steps per Workflow. Instead of just working around them, we asked the Workers and Workflows teams to raise them — which they did. Subrequests now go up to 10 million on paid plans; Workflows now default to 10,000 steps, configurable to 25,000.
The cdnjs pipeline runs on the same building blocks anyone can use: Workers, Workflows, R2, KV, Queues, Containers, and Durable Objects. The limits we hit are limits we lifted for everyone. If the Cloudflare Developer Platform can serve 9 billion requests a day and publish packages with hundreds of thousands of compressed, minified files, it can probably run whatever you're building.
What’s next
There's an obvious next question hiding in all of this: could cdnjs also serve modern, browser-native ES modules? The same packages, transformed on publish, ready to import without a bundler. The architecture doesn't rule it out. The Workflows-plus-Containers pattern that pre-compresses files today would work just as well for transforming them. We're not committing to it, but it's the kind of thing that's now possible to consider, which wasn't true a year ago.
git commit -m "with love" --author="cdnjs team"
We follow every open issue on GitHub and we want your feedback. Don't hesitate to contribute and help make the Internet better for everyone.
Should You Use AI for a Task? Here’s a Simple Way to Decide
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/should-you-use-ai-for-a-task-heres-a-simple-way-to-decide.html
This essay originally appeared in The Guardian.
I teach public policy at the Harvard Kennedy School and the Munk School at the University of Toronto. And it will come as no surprise to you that my students regularly use AI to complete their writing assignments. Doing so is a waste of their tuition money. But if their entire career is going to include AI writing assistants, why shouldn’t they embrace their future?
The best way I’ve found to explain the dilemma comes from the AI researcher Daniel Meissler: it’s the difference between work and the gym.
At work, if your job is to move a bunch of heavy things from one side of the room to another, you should use whatever assistive tech you have on hand: a wagon, a forklift… even an AI-powered robot. But at the gym, it makes no sense for that robot to lift weights for you. The point of weightlifting isn’t to move heavy things across the room; it’s to actually lift those heavy things.
The same analysis holds for any task an AI can do for you. If it’s work—if the task has to be done and no one cares how—then it’s fine to use AI assistance. But if the task is more like the gym, and how the task is done is at least as important, then it probably doesn’t make sense to use AI.
This, of course, assumes that the AI is actually up for the task and that it’s trustworthy: that it can do the job well, that its mistakes are minimal and correctable, that it’s been secured from cyber-attacks that would influence its results. Those are all important, and shouldn’t be minimized. There’s no point giving an AI something that it can’t do reliably. But once you’re confident that the AI can perform the task, the work vs. gym distinction helps you decide if it should.
The writing assignments I give my students are gym tasks, not work tasks. I ask them to write policy memos not because the world needs more policy memos. I assign them because the very act of writing, which includes thinking and outlining and drafting and editing, making and criticizing and revising arguments, will help develop the critical thinking skills they will need in their future careers. And without this constant mental exercise, those skills will atrophy. Employers are already noticing.
Reading the assignments they turn in, I can see those skills either flourishing or atrophying in my students. At least today, I can pretty easily tell the difference between an AI-written memo and a student-written one—especially if the student just turns in what the chatbot produces. It’s a catchy, plausible, grammatically perfect essay that’s not particularly well-crafted or logically coherent—and with all the tells of mid-2026 AI-generated writing.
But it’s precisely because I have spent years developing my own writing skills that I’m able to identify prose that sounds great but doesn’t actually make sense. My students don’t have that skill; they mistakenly view a confident, well-written essay as evidence of the quality of their ideas. They see the AI as cleaning those ideas up, getting them through that uncomfortable stretch of having to turn those ideas into prose. What the students miss is that their initial discomfort is a normal and healthy stage of writing, and not something to quickly get beyond. The very act of struggling with how to express what they think is an important part of the process. It’s how they test out their ideas, examine their hypotheses, and actually figure out what they think. Homework is not work; it’s the gym.
Work vs. gym also helps us understand the problem facing creatives of all kinds.
Most of the time when someone hires a writer, they just need the words. They need an instruction manual for a piece of equipment, a detailed sales presentation, a government-mandated disclosure document, or a legal brief. They need dry, predictable, accurate writing: a piece of work, exactly what AIs are good at today and what I don’t want in my student assignments. Only sometimes is writing an art form—a book, a poem, an uplifting political speech. That kind of writing is more like the gym: process matters just as much as product.
For most of human history, the only option for all of these tasks was human writers. We hired one regardless of whether we needed work writing or gym writing. And that paid a lot of writers’ salaries. I know fiction writers who supported that poorly paying career with lucrative technical writing work. Now, for the first time in human history, we can separate out when we need writing as work and when we want writing as gym. And if AI can do most of the work-type writing, society doesn’t need as many human writers.
It’s the same for visual artists. Sometimes we need an actual artist, but most of the time we just need an image: a corporate mascot, a “beware of the dog” sign, or a packaging label. Historically we gave those jobs to artists, and sometimes beautiful art resulted. But most of the time it was just work. And, as it turns out, the world needs less pure art than simple images.
Explaining the problem isn’t the same as providing the solution. I give my students the “work versus gym” speech every class, but they still use AI. I have sympathy: assignments are hard, everyone is overworked and overstressed, and—most importantly—students feel like they’ll look bad in comparison if their peers are all using AI. Even if they don’t want to use the technology, they feel like they have no choice.
There’s also an incentive problem. No one pays us to go to the gym; maintaining healthy habits requires discipline. For me, the payoffs to exercise—fewer aches and pains, less fatigue, better mood/stress management—might make me a better writer and teacher, but they’re subtle and easy to miss. For my students, incremental improvements in their reasoning and writing are equally subtle.
We do have a choice. We can look at the tasks of our lives and separate them into work or gym. Just as we might choose to use the stairs instead of the elevator, or walk instead of calling an Uber, we can wall off our cognitive gym tasks from AI and ensure that we don’t lose our skills to this technology. And we can do the same when we assign a job to someone else. If it’s a work task, we can have AI do it. If it’s a gym task, it’s a waste of everyone’s time to give it to an AI because no one learns or gets stronger as a result.
Similarly, a future where AI generates words and images is one where society has to make choices about how it will treat its creatives. This won’t be the first time—today there is minimal demand for portrait painters, for example—but maybe this time we can make different, more deliberate, choices about the value of art in our society.
AI is going to fundamentally change the nature of work. Not nearly as fast as the AI companies want you to believe, but eventually it will. Policy analysis will definitely involve AI from now on, and my students need to reimagine what it means to learn and practice that skill. More generally, the line between work and gym will change in the future as we humans adapt ourselves to a world with these new intelligences.
But for now, the work vs. gym distinction is pretty clear. Use it on yourself.
Critical VMware vCenter Vulnerabilities Allow Authentication Bypass and Remote Code Execution (CVE-2026-59309, CVE-2026-59310)
Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/etr-critical-vmware-vcenter-vulnerabilities-allow-authentication-bypass-and-remote-code-execution-cve-2026-59309-cve-2026-59310
Overview
On July 29, 2026, Broadcom published security advisory VMSA-2026-0006 addressing multiple vulnerabilities in several VMWare products. Included in the advisory are two critical remotely exploitable vulnerabilities affecting VMware vCenter Server: CVE-2026-59309 and CVE-2026-59310. Both vulnerabilities carry CVSSv3.1 base scores of 9.8 and can be exploited by unauthenticated attackers with network access to a vulnerable vCenter Server.
|
CVE |
CVSSv3.1 |
Description Summary |
|---|---|---|
|
CVE-2026-59309 |
An authentication bypass vulnerability in the VMware Directory Service of vCenter that could allow a remote attacker to bypass authentication and gain unauthorized access to the vCenter management plane. |
|
|
CVE-2026-59310 |
A directory traversal vulnerability in the vCenter Syslog server that could allow an attacker with network access to execute arbitrary code. |
VMware vCenter Server provides centralized management for VMware vSphere environments, allowing administrators to manage ESXi hosts, virtual machines, resource allocation, availability, and other virtualization infrastructure from a central control plane. Compromise of vCenter can therefore provide an attacker with significant control over the virtualized environment and its associated workloads.
Both vulnerabilities are particularly significant because exploitation does not require prior authentication. However, an attacker must have network access to the affected vCenter services. Management interfaces such as vCenter are commonly restricted to internal or dedicated management networks, which can reduce exposure to internet-based attacks but does not mitigate the risk from an attacker who has already established access to an organization’s network.
At the time of publication, there is no known evidence of exploitation or scanning in the wild for either CVE-2026-59309 or CVE-2026-59310. There is also currently no known public proof-of-concept exploit code. However, vCenter Server has appeared on CISA’s KEV list ten times in the past for other vulnerabilities, so it is known that attackers target critical issues in this product. Customers running affected VMWare products are urged to patch on an urgent basis before exploitation in-the-wild occurs.
Mitigation guidance
Organizations running VMware vCenter Server should prioritize applying the updates identified by Broadcom in VMSA-2026-0006 on an urgent basis. Broadcom states that there are no workarounds for CVE-2026-59309 or CVE-2026-59310, making vendor-provided updates the primary remediation.
|
VMware Product |
Component |
Version |
Running On |
Fixed Version |
|
VMware Cloud Foundation, VMware vSphere Foundation |
vCenter |
9.1.x.x |
Any |
|
|
VMware Cloud Foundation, VMware vSphere Foundation |
vCenter |
9.0.x.x |
Any |
|
|
VMware vCenter |
N/A |
8.0 |
Any |
|
|
VMware Cloud Foundation |
vCenter |
5.x |
Any |
Async patch to 8.0 U3k |
|
VMware Telco Cloud Platform |
vCenter |
3.0, 4.x, 5.0.x, 5.1.x |
Any |
Refer to KB449886 |
|
VMware Telco Cloud Infrastructure |
vCenter |
3.0 |
Any |
Refer to KB449886 |
For the latest mitigation guidance, please refer to the vendor advisory.
Rapid7 customers
Exposure Command, InsightVM, and Nexpose
Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-59309 and CVE-2026-59310 on VMware vCenter Server, Cloud Foundation, and vSphere Foundation products with unauthenticated vulnerability checks expected to be available in the July 30 content release.
Updates
-
July 30, 2026: Initial publication.
The Town That Wants a Data Center Next Door
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=oYlFZ_7Hrq8
Някои го предпочитат горещо
Post Syndicated from original https://www.toest.bg/nyakoi-go-predpochitat-goreshto/
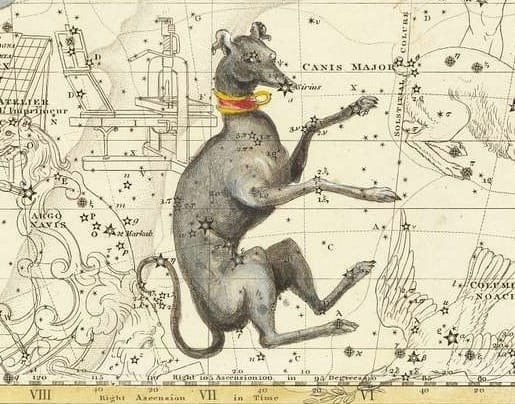
Посред лято е почти непосилно да се мисли и говори за друго освен за жегата – пък било то и на различни езици. Горещините, които наскоро обхванаха Европа, въпреки унищожителните си последствия, поне в това отношение се оказаха доста благодатни – предоставиха ни „гореща“ дума с древна и звездна история, която да разнищим, преди да излезем във ваканция до есента. Това, разбира се, е
la canicule – терминът, с който горещата вълна се нарича на френски, но благодарение на историческите температурни рекорди, регистрирани във Франция това лято, придоби международна известност.
Както се отбелязва в статията Scenes from La Canicule in Paris в The New Yorker от края нa месец юни, точният френски превод на „гореща вълна“ е vague de chaleur, докато la canicule е стар – и според автора „закачлив“ – термин, който просто добре описва днешната климатична криза. Като английски еквивалент на понятието, идващо от латинската canicula (тоест „женско кученце“), статията предоставя dog days – буквално „кучешки дни“.
Изкушаващо е да предположим, че „кучешките дни“ са нещо като антоним на „кучешкия студ“. Оказва се, обаче, че произходът както на canicule, така и на dog days всъщност не е свързан с четирикраките ни домашни любимци (или поне не директно), а (отново) със звездите. И по-точно със съзвездието Голямо куче, известно като Canis Major на латински. Неговата най-ярка звезда (и най-ярката на небосклона изобщо) е Сириус (от старогръцки Σείριος (Seirios), тоест „блестящ, изгарящ“), известна и като Кучешка звезда – Κῠ́ων (Kúōn) на старогръцки и Canicula на латински. Забелязвайки, че през горещите дни на юли и август тази звезда изгрява едновременно със Слънцето, древните гърци и римляни решили, че комбинираната светлина от двете небесни тела причинява екстремните летни жеги.
Ето как изразът „кучешки дни“ първо се появява на старогръцки като κυνάδες ἡμέραι (kynádes hēmérai), оттам калкиран преминава в латински като dies caniculares, а след това се разпространява и в други езици.
В повечето германски езици идиомът също навлиза като калка: освен на английски го срещаме и на немски (Hundstage), холандски (hondsdagen), датски (hundedagene), норвежки (hundedagene) и исландски (hundadagar)¹.
За разлика от тях, романските езици използват за летните жеги латинското наименование на самата звезда, с малки вариации: освен във френски то се употребява в испански и португалски (canícula), италиански (canicola) и румънски (caniculă)².
Латинската заемка съществува дори и в разговорния унгарски (kánikula), където се използва съвсем редовно. Тя също така се среща и в полския (kanikuła), чешкия и словашкия, а даже и в словенския, хърватския и сръбския (kanikula/„каникула“), но там се смята за по-рядка, книжовна и архаична дума. По-често срещаните наименования на горещите дни в тези езици – psie dni (полски и словашки), psí dny (чешки), pasji dnevi (словенски) или pasji dani/„пасји дани“ (хърватски и сръбски) – са калки на dies caniculares, само дето „кучето“ е станало „пес“.
Взетото назаем латинско наименование на Кучешката звезда навлиза също и в източнославянските езици, където обаче претърпява изключително изненадваща трансформация. Оригиналното му значение там постепенно избледнява, а през XIX век бива изцяло подменено. По тази причина в наши дни понятието – „канікули“ на украински, „канікулы“ на белоруски и „каникулы“ на руски – е изключително популярно, но не като определение за жега, а само и единствено със значението „ваканция“. Като доказателство за пълното скъсване на връзката с първоначалната дефиниция и произхода на думата, освен „летние каникулы“ в руския език съществуват и де факто оксиморонните „зимние каникулы“ и „весенние каникулы“.
В българския език Кучешката звезда и кръстените на нея дни се промъкват тук-там, но така и не се установяват като официално наименование за горещините,
които обикновено се наричат просто така – „горещини“. Освен това прозаично наименование, във фолклорната традиция съществува и по-поетичното Горещници, чието значение се припокрива с dies caniculares, но само донякъде. Докато за „кучешките дни“ се смята, че продължават между 30 и 60 дни, обикновено от началото на юли до средата на август (а както видяхме тази година, може да започнат още през юни), датите и времетраенето на Горещниците са строго определени – трите дни между 15 и 17 юли (или между 29 и 31 юли по стар стил), независимо какви са температурите точно тогава. Освен от етнографска гледна точка (заради ритуалите за предпазване от огън и мълнии, които се извършват в тези дни) Горещниците са интересни и от езикова: с алтернативните си имена Блъсъци и Германовци, породени от вярването, че огънят слиза от небето под формата на светкавица, и от почитането на свети Герман като повелител на гръмотевиците.
Като говорим за горещини и кучета, няма как да не споменем друго вносно понятие, което, за разлика от canicule и dog days, се е установило в българския език доста успешно. Това, разбира се, е иконичният хотдог, понякога шеговито превеждан буквално като „горещо куче“³. При него кучешката връзка си е съвсем директна. Смята се, че наименованието hot dog идва от формата на кренвиршите, сходна с външния вид на кучетата от порода „Дакел“ – немските имигранти ги внесли в Америка по същото време като вурстовете, които слагали в сандвичите. Според друга теория сандвичите получили името си поради съмнения, че въпросните вурстове съдържали кучешко месо.
Но в българския език все пак съществува животно, чието наименование споделя латински корен с кучето (canis), макар и да няма нищо общо с него. За моя – а предполагам и ваша – голяма изненада, това е канарчето. Птичката, оказва се, е кръстена на Канарските острови, откъдето произхожда – а не обратното, както аз наивно (като едно същинско канарче) предполагах.
Името на самия архипелаг – Islas Canarias на испански, от Canariae Insulae на латински – в превод наистина означава „Острови на кучетата“. Но докато този факт е неоспорим, то теориите относно това какво точно представляват въпросните кучета, са доста противоречиви. Една от тях цитира римския историк Плиний Стари, който в своята „Естествена история“ от около 77 г. описва експедиция до остров Canaria, кръстен така „заради множеството кучета с огромни размери“, на които се натъкват изследователите. Според други теории древните римляни слагали всякакви страшни морски твари под общия знаменател canes marini („морски кучета“) и всъщност е по-вероятно животните на острова да не са били кучета, а тюлени. В трета версия пък се твърди, че името е заето от берберското племе Canarii, което обитавало острова, впоследствие наречен Gran Canaria и дал името на целия архипелаг⁴. Но все пак, ако съдим по двете кучета, изобразени на герба на Канарските острови, изглежда, че най-надеждна или поне предпочитана версия е тази с реалните кучета⁵.
Размишлявайки върху други думи в българския, които евентуално споделят латинският корен canis, се запитвам дали би могло такова да е прилагателното „кански“. Все пак го използваме подобно на „кучешки“ – с подсилващ ефект и като цветист синоним на „голям“ или „як“. Неговият произход обаче – този път настина – се оказва птичи. Според Българския етимологичен речник, наречието „кански“ произлиза „от каня ‘вид граблива нощна птица‘, поради пронизителния ѝ крясък“ и следва да се използва „само в изразите пищя кански, плача кански“. В по-нова публикация на Института за български език обаче, освен че грабливата птица правилно е идентифицирана като „дневна“, се потвърждава моето предположение, като се отбелязва: „Постепенно употребата на кански в преносното му значение се разширява и то получава значение ‘извънредно голям’“. Като илюстрация в публикацията са предложени следните примери: „кански усилия“, „кански мъки“, „кански труд“, „кански студ“ и др.
По тази логика словосъчетанието „канска жега“ става съвсем приемливо. И дори да не споделя обща етимология със съзвездието Canis Major, двете поне имат сходно звучене.
1 Любопитно изключение прави шведският, в който вместо калка на dies caniculares, изразът за най-горещия период от годината е Rötmånaden, тоест „Месец на гниенето“ – заради склонността на храната да се разваля в жегата. (Такава е идеята и зад думата във фински – mätäkuu, която означава същото.) В шведски съществува и изразът hundår, буквално „кучешка година“ или „кучешки години“, който обаче означава съвсем друго: труден период, в който човек трябва да работи здраво и да търпи лишения, за да постигне определена цел.
2 На италиански, освен като canicola, големите летни горещини са известни и като solleone: от Sole + Leone, или периодът, в който Слънцето е в съзвездието на зодия Лъв. Като виден представител на зодията това ми е особено симпатично – най-малкото защото ми предоставя алтернативно и доста по-ведро астрологическо наименование за Сатурновата дупка и ретроградния Меркурий, който тази година започна на 29 юни и продължи до 23 юли.
3 В английския срещаме и доста забавен „синонимен“ термин на понятието hot dog, а именно: dog in heat (буквално „куче в горещина“), което обаче означава „разгонена кучка“.
4 Самият Плиний Стари в своята „Естествена история“ също споменава берберското племе Canarii, твърдейки, че то е наречено така заради сходната му хранителна диета с „кучешката раса“. Пак там той използва производни на думата canis („куче“) за акули – за по-едрите употребява определението canis marinus („морско куче“), а по-дребните, които днес наричаме „морски котки“, „бодлоперки“ или „дънни акули“, той нарича canicula. Енциклопедията, бидейки енциклопедия, разбира се, описва и как изгряването на звездата Canicula в разгара на лятото носи непоносими горещини, кара кучетата да побесняват и влияе на реколтата.
5 Оказва се, че на Канарските острови е кръстен и лондонският финансов квартал Canary Wharf (буквално „Канарски пристан“), който се намира на Isle of Dogs („Остров на кучетата“). Името му се дължи на това, че в миналото там са акостирали корабите, превозващи плодове от Канарските острови.
В рубриката „От дума на дума“ Екатерина Петрова търси актуални, интересни или новопоявили се думи от нашето ежедневие и проследява често изненадващия им произход, развитието на значенията им във времето и взаимовръзките им с близки и далечни езици.
[$] LWN.net Weekly Edition for July 30, 2026
Post Syndicated from jzb original https://lwn.net/Articles/1084315/
Inside this week’s LWN.net Weekly Edition:
- Front: Hazard pointers; DFSG team; Swap devices; Netkit and BPF; BPF inlined functions; Fedora GRUB; gccrs.
- Briefs: RIP Dan Williams; Debian LLM resolution; Fedora 45 process; Codeberg LLM policy; GCC LLM policy; GNU Binutils 2.47; GNU C Library 2.44; Wayfire 0.11; Quotes; …
- Announcements: Newsletters, conferences, security updates, patches, and more.
Crowdsourced taxonomy verification: A feedback-driven framework for refining knowledge graph relationships via online search interactions
Post Syndicated from Grab Tech original https://engineering.grab.com/crowdsourced-taxonomy-verification
Introduction
The efficacy of semantic search relies on the accuracy of the underlying Knowledge Graph (KG). In high-velocity domains like on-demand food delivery or e-commerce, the catalog of entities like dishes, products, and merchants changes rapidly.
Current methods for KG construction and maintenance face three critical challenges:
-
Inaccuracy and hallucination from Large Language Models (LLMs): Automated models often infer relationships based on statistical text co-occurrence rather than semantic reality. For instance, an LLM might incorrectly classify “Pho” as a child of “Italian Noodle Soup” due to linguistic similarity, leading to irrelevant search results.
- Scalability limits of manual verification: Traditional verification relies on human annotators or domain experts. This approach is slow, expensive, and unable to keep pace with dynamic catalogs containing millions of entities. For example, daily changes in restaurant menus or grocery stock keeping units (SKUs).
- Error propagation in ranking: Inaccurate graph edges propagate errors downstream. If a parent-child relationship is wrong, query expansion algorithms will retrieve irrelevant items, directly degrading Click-Through Rate (CTR) and user trust.
We introduce a feedback-driven verification engine that operationalizes the search interface as a validation environment. Key contributions include:
-
User feedback-driven verification: The system treats unverified graph edges as hypotheses. Instead of accepting them as truth, it tests them against live traffic by injecting them into search suggestions and measuring user engagement.
-
Hierarchical relationship refinement: Unlike systems that only validate entities (nodes), this framework validates structural links (edges). It confirms whether entity A is truly a parent, child, or sibling of entity B, ensuring structural integrity.
-
Adaptive exploration: The system employs a greedy exploration policy. It intelligently balances exploitation by showing known good results with exploration through injecting unverified candidates to gather data without degrading the user experience.
Background
Automated KG construction using LLMs and unstructured content extraction can scale quickly across large, dynamic catalogs. However, relationships inferred from text co-occurrence or vector similarity do not always reflect semantic reality. Manual verification by domain experts remains accurate but does not scale to millions of entities that change daily.
When inaccurate edges enter the graph, ranking and query expansion systems propagate those errors to users. Incorrect parent-child or sibling links lead to irrelevant search results, reduced CTR, and lower user trust. An additional solution is required that can validate graph structure continuously, at scale, without relying solely on manual curation.
Solution
The overall workflow of this invention is shown in the following figure. The details of each step are explained in this section.
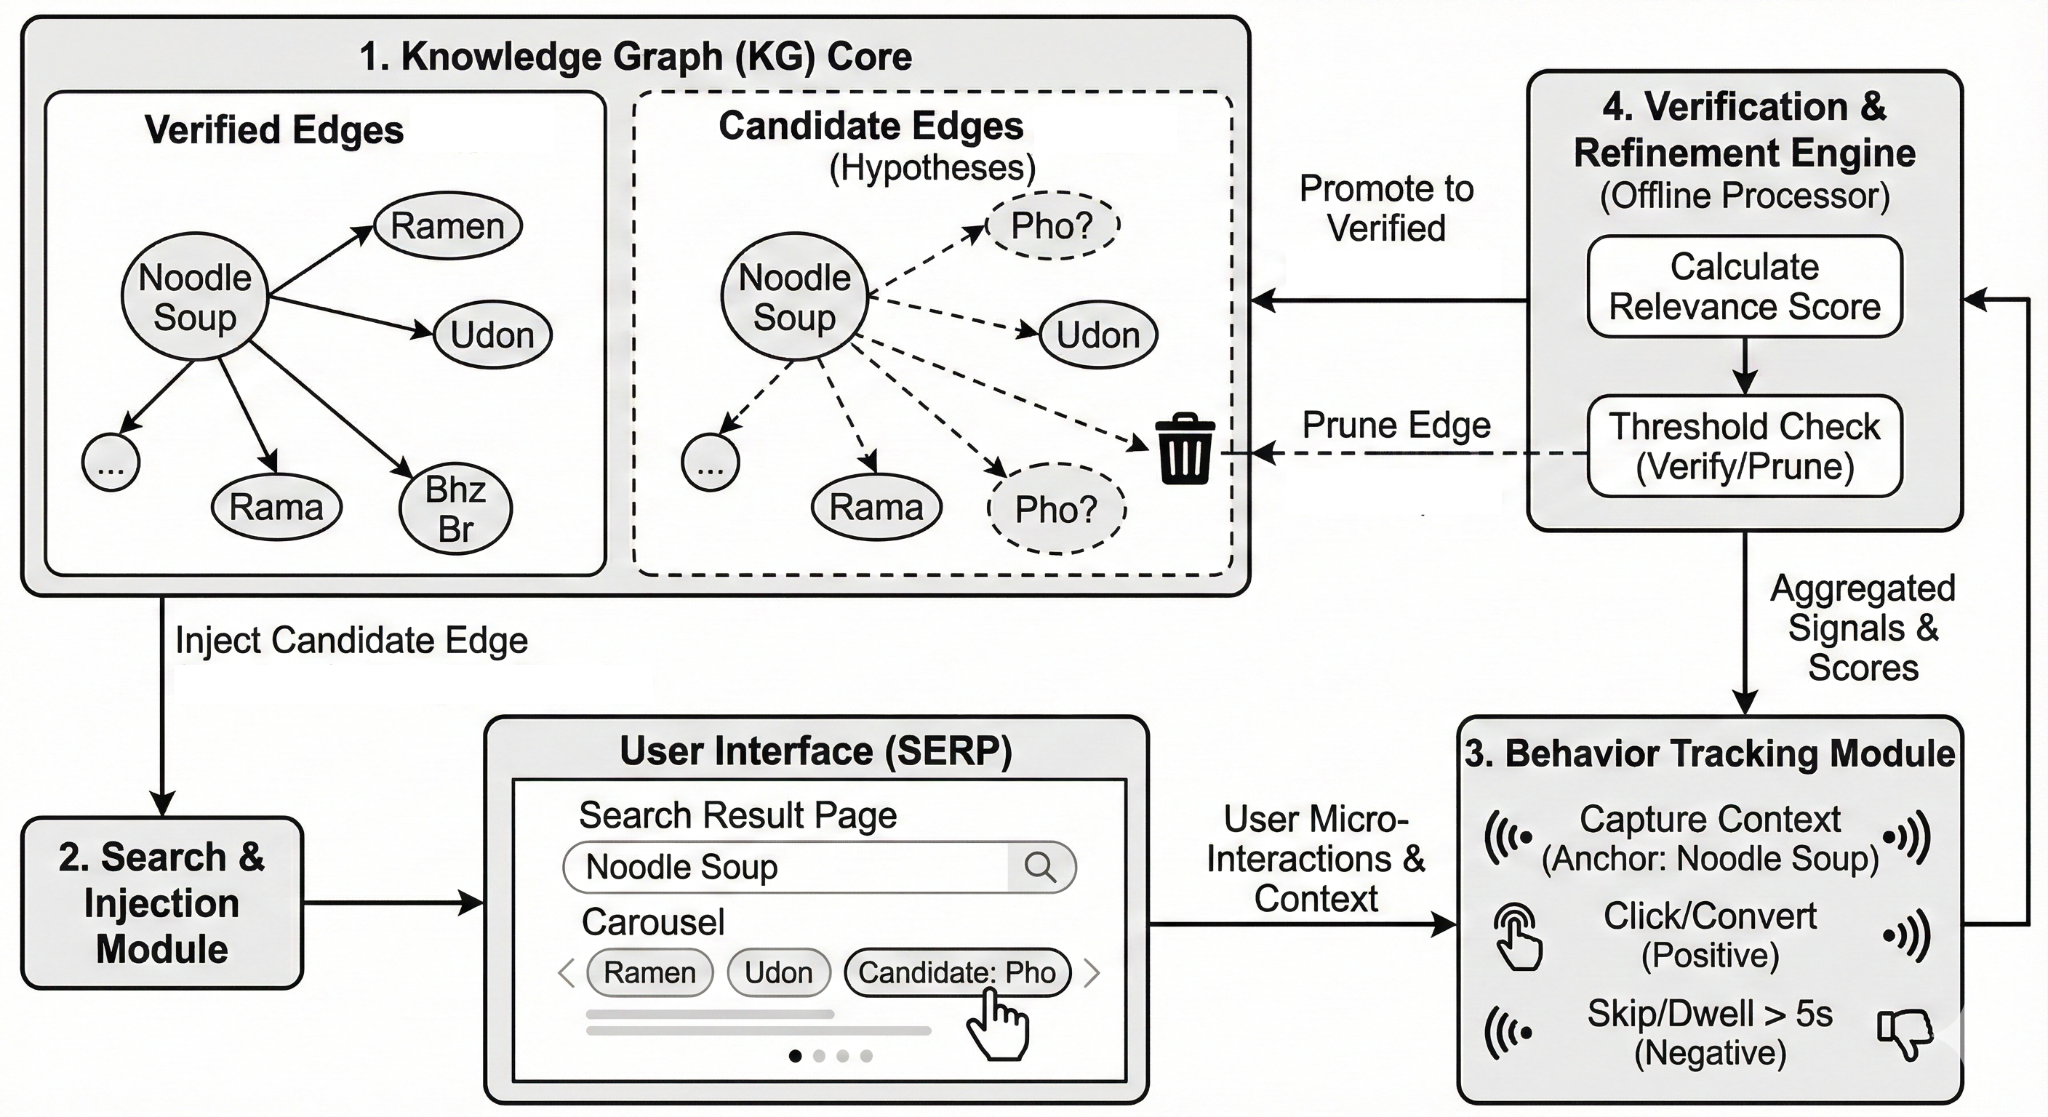
The proposed framework functions as a closed-loop validation ecosystem. It is composed of four integrated modules designed to continuously cycle data from the KG to the user interface and back, using real-world interactions to separate semantic truth from artificial intelligence (AI) hallucinations.
The verification process follows a continuous, iterative loop that cycles data from the backend graph to the frontend user interface and back. This four-step procedure operationalizes the human-in-the-loop validation mechanism:
- Hypothesis generation
- Candidate injection
- Signal aggregation and scoring
- Graph update logic
Architecture details
KG core
The central repository acts as the source of truth, storing entities such as dishes, products, or merchants, and the connections between them. To manage the verification process, the system introduces a specialized metadata layer that classifies every connection (or edge) into one of two distinct states:
- Verified edges: These are established relationships that have been validated either by high historical traffic or human confirmation. They represent the safe structure of the graph. For example, “Sushi” is definitely a child of “Japanese Cuisine”, and is used to power standard search results.
- Candidate edges: These are probabilistic, unverified relationships generated by automated LLMs or content scrapers. They are treated as hypotheses waiting to be proven. For example, if an LLM ingests a blog post and predicts that “Pho” is related to “Italian Noodle Soup,” this link is stored as a candidate edge, invisible to the main search algorithm until validated.
Search and injection module
This module sits between the KG and the user, intercepting the query execution pipeline. Unlike standard ranking algorithms, which strictly optimize for relevance by showing only the best results, the injection engine employs a balanced strategy known as exploration vs. exploitation.
- The injection mechanism: When a user performs a search, the system retrieves a list of high-confidence results (exploitation). Simultaneously, it deliberately retrieves a small subset of candidate edges related to the query. It injects these unverified candidates into specific, lower-risk slots within the user interface, such as the third or fourth position in a related searches chip carousel.
- Risk management: To prevent user frustration, the system limits the number of candidates shown per session. This ensures that the user is primarily served helpful, verified content, while still providing enough data points to test new hypotheses.
Behavior tracking module
To accurately measure whether a candidate relationship is valid, the system tracks user micro-interactions with high granularity. It captures not just the final click, but the precise context in which the interaction occurred to determine semantic intent.
- Contextual anchoring: The system logs the specific search term, also known as the anchor, used by the user. A click on “Pho” is only counted as a vote for the relationship if the user was searching for “Noodle Soup” at the time.
- Signal classification: Signals are assessed in aggregate to estimate the relevance of a candidate relationship. Higher-intent engagement contributes stronger positive evidence, lighter exploratory behavior contributes weaker positive evidence, and lack of engagement or explicit negative actions contributes negative evidence.
Verification and refinement engine
This is an offline processing unit that acts as the final judge. It aggregates thousands of individual user signals to update the topology of the KG.
Relevance scoring: Instead of complex formulas, the engine calculates a simple confidence ratio. It looks at the total number of times a candidate was shown versus the number of positive interactions it received.
Graph topology updates:
- Promotion (verify): If the confidence ratio exceeds a verification threshold. For example, if the candidate performs as well as known good items, the edge is upgraded from candidate to verified. It becomes a permanent part of the graph and is shown to all users.
- Demotion (prune): If the candidate consistently fails to garner engagement or receives negative signals, it falls below a pruning threshold. The system automatically deletes this edge, effectively correcting the AI’s hallucination and cleaning the dataset.
Implementation
Hypothesis generation
The process begins by identifying a target subject, referred to as the anchor entity. For example, the specific dish “Pho”. The system queries the KG to retrieve a set of potential relationships. This retrieval includes both verified neighbors, where relationships are already confirmed by experts, and candidate neighbors, where the relationships are predicted by AI models but not yet proven.
Candidate injection
Once a hypothesis is selected, the system exposes it to real users to gather evidence. When a user actively searches for the anchor entity, the system dynamically injects the candidate neighbor into the search results.
- User interface (UI) implementation: The candidate is presented alongside verified items, typically in a related categories carousel or a refine search chip list. This reflects standard relevance experimentation in search, with safeguards to ensure the experience remains controlled and measurable.
- Exposure logging: The system logs an impression event specifically linking the anchor to the candidate. This record serves as the baseline, documenting that the user saw the relationship, which is essential for calculating future engagement rates.
Signal aggregation and scoring
Instead of using a raw count of clicks, the system calculates a sophisticated relationship confidence score by aggregating user interactions over time. This scoring model uses a weighted tier system to distinguish between casual interest and strong intent.
- Weighted interaction logic: The system assigns a higher value to actions that require more effort or commitment. For example, a “Purchase” or “Add-to-Cart” action is weighted significantly heavier than a simple click, as it indicates a strong validation of the relationship. Conversely, scrolling past the item quickly or skipping is treated as a negative signal.
- Normalization: To ensure fairness, the total weighted score is normalized against the total number of times the candidate was shown. This prevents niche items with low total traffic but high accuracy from being unfairly penalized.
Graph update logic
Periodically, the verification engine evaluates the confidence score against predefined benchmarks to update the KG’s topology. This is a binary decision process:
- Validation (cementing the edge): If the accumulated confidence score exceeds a strict validation threshold, the system concludes that the relationship is genuine. The status of the edge is updated from candidate to verified. This permanently adds the relationship to the graph, ensuring it appears in future standard searches without the need for further testing.
- Rejection (pruning the edge): Conversely, if the score falls below a rejection threshold, indicating that users consistently ignore or reject the suggestion, the system concludes the relationship is an AI hallucination. The edge is severed or removed from the graph. This pruning action cleans the dataset, preventing the system from making the same bad recommendation again.
Case study: hierarchical refinement in food delivery
To demonstrate the framework, consider a validation scenario in food delivery taxonomy. An LLM-based ingestion pipeline flags a candidate parent-child link
Noodle Soup → Dry Mee Pok and stores it as an unverified candidate edge in the KG, ready for live validation.
User-triggered validation:
When a user searches for “Noodle Soup,” the search module injects the candidate alongside verified results. For example, in a “Refine by Dish” filter carousel, and logs an impression linking the anchor query to the candidate.
Outcome collection:
User interactions like clicks, dwell time, scroll behavior, and conversions are captured and weighted over the validation window. The verification engine aggregates these signals and updates the graph: relationships that meet the validation threshold are promoted to verified status; those that fail are pruned or re-mapped to a more appropriate parent node.
Impact
By injecting unverified candidate edges into live search results and recommendation interfaces via a multi-armed bandit (MAB) exploration strategy, the system leverages implicit user feedback to validate semantic truth. This dynamic, human-in-the-loop mechanism effectively prunes erroneous connections and reinforces accurate taxonomies without the need for manual curation, significantly enhancing search relevance in dynamic domains such as food delivery and retail.
The case study demonstrates how the framework validates candidate relationships through live user traffic, collecting interaction signals and updating the graph without manual curation.
Learnings and conclusion
The feedback-driven verification engine operationalizes the search interface as a validation environment for KG relationships. By classifying edges as verified or candidate, injecting candidates through an exploration vs. exploitation strategy, and aggregating weighted user signals, the system promotes accurate relationships and prunes AI hallucinations at scale.
Unlike approaches that validate only entities, this framework validates structural links, confirming whether entity A is truly a parent, child, or sibling of entity B. The food delivery case study shows how a user-triggered search can initiate validation and outcome collection at scale, without manual intervention.
What’s next
Hierarchical confidence tiers
To safely graduate new connections into the production graph, we are introducing a dual-measurement trust system that requires both volume and variety before a new connection goes live: support mass (product hits, graph depth, recency) and corroboration (unique sessions, anonymous cohorts, and temporal spread). Connections must climb a strict state machine: proposed → shadow eligible → canary eligible → production, advancing only when both metrics meet progressively higher thresholds; if a snapshot causes metrics to fall below a tier’s floor, the connection is automatically demoted.
Adversarial and spam resistance
To prevent bad actors, bots, or highly repetitive users from manipulating the search graph, we are building a multi-layered defense system. We enforce per-merchant rate limits and anti‑abuse controls: hourly caps per session/device, exponential backoff for rapidly repeated actions, and a short (few‑hour) freeze of promotions from any user cohort after declines or “irrelevant” signals. For bot and Sybil attack defense, traffic flagged by abuse systems is excluded from trust calculations (but logged for analysis); votes must come from diverse network subnets or cohort buckets, and each bucket is subject to a daily contribution cap.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
The No-Limits President Hits His Limits
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/QaD2xhyLW9o
Amazon identifies North Korean hacker group behind open-source supply chain attacks
Post Syndicated from CJ Moses original https://aws.amazon.com/blogs/security/amazon-identifies-north-korean-hacker-group-behind-open-source-supply-chain-attacks/
Amazon is sharing new findings about how a threat actor linked to the Democratic People’s Republic of Korea (DPRK) is targeting open source software libraries, the shared building blocks that companies around the world use to develop applications. Amazon Threat Intelligence has linked several recent compromises of popular Node Package Manager (NPM) libraries to the same DPRK-linked threat actor, a connection that hasn’t been publicly reported until now. The analysis also describes how generative AI is already changing what malicious software packages look like and how threat actors are beginning to probe AI-based code systems. We’re sharing this research to help the open source community and security teams better identify and address these types of events.
These developments come 2 years after the XZ Utils backdoor, which demonstrated how a patient attacker can compromise critical open source software by exploiting the trust and limited time of volunteer maintainers. Open source software underpins much of the internet’s infrastructure: operating systems, web servers, encryption libraries, and the application frameworks that businesses rely on daily. When an attacker compromises a widely used open source package, every organization that depends on that package is potentially affected. Since then, Amazon Threat Intelligence has observed the volume and sophistication of software supply chain attacks increase, driven in large part by DPRK‑linked threat actors and cybercriminal groups.
In this post, Amazon Threat Intelligence and the Amazon Inspector team share new details about recent campaigns against popular NPM packages, including evidence that the compromises of the axios, debug, chalk, and typo-crypto libraries were carried out by the same DPRK-linked threat actor tracked by the security community as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. We also outline how the techniques used to compromise open source repositories are evolving, why these changes matter for organizations that depend on open source software, and what Amazon Web Services (AWS) is doing to help customers detect and respond to these threats.
One DPRK–linked group behind multiple NPM compromises
In March 2025, the DPRK-linked threat actor compromised the typo-crypto package. In September 2025, the same threat actor compromised the debug and chalk NPM packages. In March 2026, the same operational playbook appeared in a compromise of the axios package, one of the most widely used JavaScript libraries with more than 100 million weekly downloads. In each case, the threat actor gained access by socially engineering a trusted maintainer of the package, then published a software update containing malicious code. Any organization that automatically pulled the latest version of these packages received the compromised update.
While the axios compromise has been publicly attributed to this DPRK-linked threat actor, the typo-crypto, debug, and chalk incidents haven’t previously been connected to it. Amazon Threat Intelligence identified shared tactics, techniques, and procedures (TTPs) across these supply-chain campaigns, including trojanized NPM packages, use of post-install hooks (scripts that run automatically when a package is installed), and code reuse. Based on analysis of command-and-control (C2) indicators and TTPs, Amazon Threat Intelligence assesses with medium confidence that these campaigns are attributable to the DPRK-linked threat actor tracked as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. This is the first time these compromises have been publicly tied to this DPRK-linked threat actor.
Amazon Threat Intelligence assesses this as part of a financially motivated pattern: by compromising a small number of highly popular packages, the group gains potential access to thousands of downstream environments simultaneously. For a financially motivated threat actor, this approach is far more efficient than targeting organizations one at a time.
The aggregate impact of these incidents underscores the efficiency of targeting share dependencies. As reported by Wiz Research, roughly 1 in 10 cloud environments were affected by the debug and chalk supply chain event within a two‑hour window.
A smaller campaign that foreshadowed later activity
During routine analysis of indicators and TTPs related to the axios threat actor, Amazon Threat Intelligence identified a connection to a domain registered in 2025, prompting a full investigation into its historical activity. That investigation uncovered that the same DPRK-linked threat actor had committed a trojanized file to the typo-crypto NPM package in March 2025. The malicious file, core.js, masquerades as the legitimate core-js NPM package within the typo-crypto repository.
Based on the limited number of observed downloads, Amazon Threat Intelligence assesses that this campaign was small scale and likely served as a testing ground for the more visible supply chain operations that followed in late 2025 and 2026. The group appears to have been refining supply chain techniques more than a year before the larger campaigns that drew public attention. Amazon Inspector reported this malware to the Open Source Vulnerabilities (OSV) database, where it’s now tracked as MAL‑2026‑3400, so that the broader security community can benefit from these findings.
The trojanized file executes when it receives a hash input beginning with the value 0098273. When triggered, it downloads a second-stage payload from a hardcoded C2 server, then executes the payload based on the victim’s operating system, with behavior tailored for Windows, macOS, or Linux. The malware implements file-based persistence with payload rotation and uses multi-layer obfuscation, combining base64‑encoded text with an XOR cipher keyed to 01042025.
Associated indicators of compromise include:
- Domain: npmjs[.]store
- IP address: 216[.]74[.]123[.]126
- NPM package: typo-crypto (SHA256: 24604384b0e748ada07923630b3d037489e696284a98c4409fb9b6763565571f)
- Trojanized file: core.js (SHA256: 2014d09c7ded74d89c885b5f11693865224116f1b25df9330e61fe528f419d73)
Amazon Threat Intelligence assesses that the group was experimenting with techniques that later appeared in the higher-impact campaigns against axios, debug, and chalk. Although the observed download volume was low, the tradecraft aligns with what we later observed in attacks on more popular packages.
How attacker tradecraft is shifting
Over the past year, Amazon Threat Intelligence and Amazon Inspector have observed threat actors changing the techniques they use to target open source libraries. These changes matter because open source packages remain attractive targets: they’re widely trusted, automatically updated in many environments, and maintained by communities that welcome new contributors. The following patterns describe how attackers are adapting their methods to evade modern defenses. Each is designed to exploit the gap between the moment a dependency is inspected and the moment it actually executes. A year ago, we looked for malicious packages. Today, we look for malicious behaviors split across packages that appear harmless on their own.
From package‑level attacks to fragment‑level attacks
Amazon Inspector has observed attackers increasingly splitting a single malicious workflow across several ordinary-looking packages. One package stores an encrypted blob disguised as configuration. A second ships the decryption logic. A third, often published later, fetches and executes the payload.
Viewed on its own, each package looks benign. There are no install hooks that stand out, no obvious evaluation of untrusted input, no network calls that look suspicious. The malicious behavior only appears when the components are used together in the intended sequence. This approach is designed to defeat scanners that evaluate packages one by one instead of reasoning about how they interact in a real dependency graph.
Long-horizon campaigns that invest in trust
We’re also observing threat actors taking a long view of trust accumulation. Instead of publishing obvious malware and waiting for downloads, they publish something genuinely useful and maintain it. They behave like real maintainers for weeks or months, shipping features, fixing bugs, and gaining dependents.
The same patience shows up on the human side. In some cases, the goal isn’t to launch a new package at all, but to become a contributor to an existing project. That’s the through line from XZ Utils backdoor to the debug, chalk, and axios maintainer compromises. In each case, the adversary treated legitimacy as an asset to be spent once, at the moment of maximum access.
Decoupling the package from its behavior
In many recent cases, a library is clean on the public registry yet still dangerous, because its real behavior depends on resources the attacker controls elsewhere. These can include guard or license scripts fetched from an external repository at runtime, configuration files that gate certain behaviors, or remote endpoints consulted at startup.
As long as those external resources remain benign, code reviews pass and automated scans return clean results. When an attacker flips the content or arms an endpoint that previously returned a placeholder, every installed copy can become malicious at once, without any new package release. A package that shows no malicious behavior today isn’t the same as a package that’s is safe by design.
From basic obfuscation to real cryptography
Where attackers used to rely on simple obfuscation such as minification or single-layer base64 encoding, we now observe multi-stage payloads that use stronger cryptographic techniques. Examples include AES‑GCM encrypted blobs gated by passphrases, RC4-style string arrays with per-call keys, layered XOR over base64, and native loaders that hold the next stage as an encrypted field decrypted only in memory.
The common design choice is that the decryption key is never stored in the package itself. It’s derived from runtime context, fetched from a server at execution time, or supplied as a license key. That means even an analyst with full source access can’t reliably decrypt the payload statically. Stage one looks like a simple decryptor; the malicious content remains ciphertext until it runs on a real target with the real key.
Payloads that avoid detonating in sandboxes
As defenders have scaled automated analysis in cloud sandboxes, attackers have made their code more environment aware. The payload decides whether it’s being analyzed before it acts. We see execution gated behind real package install lifecycles, single-use environment variables, and checks for signals of a genuine developer or build environment. These include interactive terminals, realistic usernames and hostnames, domain membership, plausible uptime, local file history, specific operating systems, and cloud metadata that helps distinguish analysis infrastructure from normal workloads.
Some delivery servers also tailor what they serve based on the client. A benign decoy goes to generic browser-like requests, while the live payload only appears for the exact user agent used by the malware. The result is that a clean verdict from a cloud sandbox often tells you more about how convincing your environment looks than how safe the package is.
How generative AI is reshaping both attacks and defenses
Generative AI is changing what attackers can produce and what defenders can rely on. Adversaries can generate novel code and content at scale. Historically, many malicious packages were caught because they looked wrong, with broken language, thin documentation, obvious copy-paste, or a telltale function reused across samples. Generative AI erases many of those signals.
Attackers can now produce thousands of lines of coherent, idiomatic, well-commented code, complete with convincing documentation, plausible commit histories, and synthetic maintainer identities, wrapped around a backdoor. Because each variant can be mutated, renamed, restructured, and re-encrypted, there is no single stable signature to match. Pattern-based detection loses ground against malware that looks one of a kind in every deployment.
AI is also creating new initial access vectors. One emerging technique is slopsquatting, where attackers register package names that exist only because an AI coding assistant hallucinated them. When a developer or an autonomous coding agent asks for help and the model confidently recommends a nonexistent package, an attacker can pre-register that name and wait. The next person who follows the recommendation might receive malware, despite not mistyping anything or visiting a malicious site, because the AI effectively delivered the bad dependency for them. As organizations move toward agents that install dependencies with limited human review, this path looks less like a curiosity and more like a scalable delivery channel.
Most significantly, AI changes the calculus for defensive automation. Attackers are no longer just writing malware for humans to miss. They’re writing malware for AI reviewers to approve. As organizations rely on AI systems to review code and triage packages, those AI systems themselves become part of the attack surface. We expect that indirect prompt injection, a technique where hidden instructions manipulate an AI system into taking unintended actions, will increasingly be embedded in malicious packages to fool AI-based code scanners. These instructions can be hidden in source comments, README files, docstrings, or test fixtures, and crafted to convince an automated system to mark malicious code as safe, skip a specific file, or perform an unintended action during analysis. The same content the malware needs to function can carry a second, separate message aimed at the machine that inspects it.
How AWS is responding
We’re investing across Amazon Threat Intelligence and Amazon Inspector to help customers adapt to this shifting landscape of software supply chain risk. Amazon remains committed to helping protect the security of our customers and the internet by actively hunting for and mitigating threats from sophisticated threat actors. We will continue working with Amazon teams, industry partners, and the security community to share intelligence and mitigate threats. Upon discovering this campaign, Amazon Threat Intelligence worked with Amazon Inspector so the malicious package was tracked, mitigated, and shared with the community through the OSV database. Additionally, the observed indicators were shared with Amazon GuardDuty to alert our customers of this activity.
Amazon Inspector uses these insights to refine our detection logic, broaden coverage across registries, and prioritize signals that reflect the tradecraft shifts described in this post, and is collaborating with industry partners such as package registries and Open Source Security Foundation (OpenSSF) to share findings.
We’re also investing in helping open source maintainers better secure their projects. In 2026, AWS joined the Linux Foundation and other industry leaders to launch Akrites, a collaborative initiative to defend critical open source software against AI-enabled cyber threats. AWS has also jointly invested $12.5 million alongside other organizations to defend the open source ecosystem from AI-driven attacks. These efforts reflect a broader commitment: the security of open source software is a shared responsibility, and defending it requires sustained investment from the organizations that depend on it.
Our goal is to help customers understand where their environments rely on open source components, identify suspicious behavior early, and respond quickly when the software supply chain is used as an entry point.
Comic for 2026.07.29 – Harry Potter
Post Syndicated from Explosm.net original https://explosm.net/comics/harry-potter
New Cyanide and Happiness Comic
Accelerate Spark on EMR Serverless with larger workers and shuffle-optimized disks
Post Syndicated from Karthik Prabhakar original https://aws.amazon.com/blogs/big-data/accelerate-spark-on-emr-serverless-with-larger-workers-and-shuffle-optimized-disks/
With Amazon EMR Serverless, you can run open source big data frameworks such as Apache Spark and Apache Hive without managing clusters or infrastructure. Customers are increasingly choosing EMR Serverless for their analytics workloads because of the simplicity of a fully managed, serverless experience. As adoption grows, teams want to bring their most demanding jobs to Serverless too. These jobs include large-scale joins, shuffle-heavy ETL, and memory-intensive analytics that previously required carefully sized clusters. Customers migrating these heavyweight workloads from their Spark clusters often need the same compute shapes on EMR Serverless to achieve the same price-performance and make migration easier.
Today, we’re excited to announce a new 32 vCPU / 244 GB worker configuration on Amazon EMR Serverless, giving you the headroom to run your most intensive workloads without leaving the serverless experience.
Overview of larger workers
An EMR Serverless application uses workers to run your Spark tasks, and you can choose a worker size that matches your workload. The new 32 vCPU worker offers a large compute and memory footprint (32 vCPUs and 244 GB of memory) that supports attaching up to 2,000 GB of shuffle-optimized disk. This combination benefits three common workload patterns:
- Shuffle-intensive workloads – Wide transformations such as
join,groupBy,sortBy, andrepartitionredistribute large amounts of data across the cluster. Larger workers keep more shuffle data local to each executor and read and write shuffle blocks on higher-throughput disk, reducing remote fetches and shuffle wait time. - I/O-heavy workloads – Queries that scan large datasets or spill intermediate data to disk are limited by disk throughput and IOPS. The shuffle-optimized disk raises the ceiling on both sides. Large workers also improve network bandwidth.
- Memory-intensive workloads – Higher per-executor memory (244 GB versus 30 GB) lets more data be cached and processed in memory without spilling, which helps with data skew and caching.
Benchmark setup
We compared the recommended large-worker configuration against common small-worker defaults at identical total compute (192 vCPUs).
- Large workers – 6 executors × (32 vCPU / 244 GB / 2,000 GB shuffle-optimized disk).
- Small workers – 48 executors × (4 vCPU / 30 GB / 200 GB standard disk).
The two configurations differ in both worker shape and disk class. We compare them as paired configurations, since shuffle-optimized disk is the intended disk type for the 32 vCPU worker. The reported gains reflect this combined effect.
Both configurations set spark.dynamicAllocation.enabled=false and spark.scheduler.minRegisteredResourcesRatio=1 to reduce variance from worker launch times. Requiring full registration ensures each query starts only after the cluster is ready. We ran every query with 3 iterations and reported the median. Both benchmarks ran on EMR release emr-7.13.0 in a virtual private cloud (VPC) with an Amazon Simple Storage Service (Amazon S3) gateway endpoint attached to the private subnets.
Benchmark results
This post presents benchmark results comparing the new 32 vCPU workers against the existing 4 vCPU standard workers using the industry-standard TPC-DS and TPC-H benchmarks. Across 126 queries (104 TPC-DS and 22 TPC-H), large workers delivered an average of 29% faster query execution and 29% lower query-attributed cost, with zero regressions and improvements peaking at 45–55% on shuffle-heavy, multi-table join queries. Both the larger executor shape and the shuffle-optimized disk contribute to these gains. The disk advantage is most pronounced on the shuffle and I/O-heavy queries where the largest improvements appear.
The following table summarizes the results across both benchmarks. Large workers won every query on both performance and cost.
Note: The benchmark results in this post are derived from the TPC-DS and TPC-H benchmark specifications. TPC-DS and TPC-H are trademarks of the Transaction Processing Performance Council.
| Benchmark | Queries tested | Avg performance improvement | Avg cost improvement |
| TPC-DS (3 TB) | 104 | 26.7% | 27.4% |
| TPC-H (1 TB) | 22 | 38.5% | 37.2% |
| Combined | 126 | 28.8% | 29.1% |
TPC-DS 3 TB benchmark
TPC-DS is an industry-standard decision support benchmark that models complex analytical workloads with multi-table joins, subqueries, and aggregations. We ran 104 queries from the TPC-DS v2.4 suite against a 3 TB partitioned Parquet dataset, with 3 iterations per query for statistical confidence.
The test environment was as follows:
- Dataset: 3 TB partitioned Parquet (24 TPC-DS tables).
- Queries: 104 (full suite minus 4 incompatible with the dataset schema).
- Iterations: 3 per query (one query per
start-job-run, a fresh Spark application each time). - Networking: VPC with an Amazon S3 gateway endpoint.
- EMR release:
emr-7.13.0.
The following chart shows the top 10 and bottom 5 queries by performance improvement. All 104 queries show a positive improvement, with the largest gains on shuffle-heavy queries such as q58 (45%), q21 (43%), and q12 (42%).
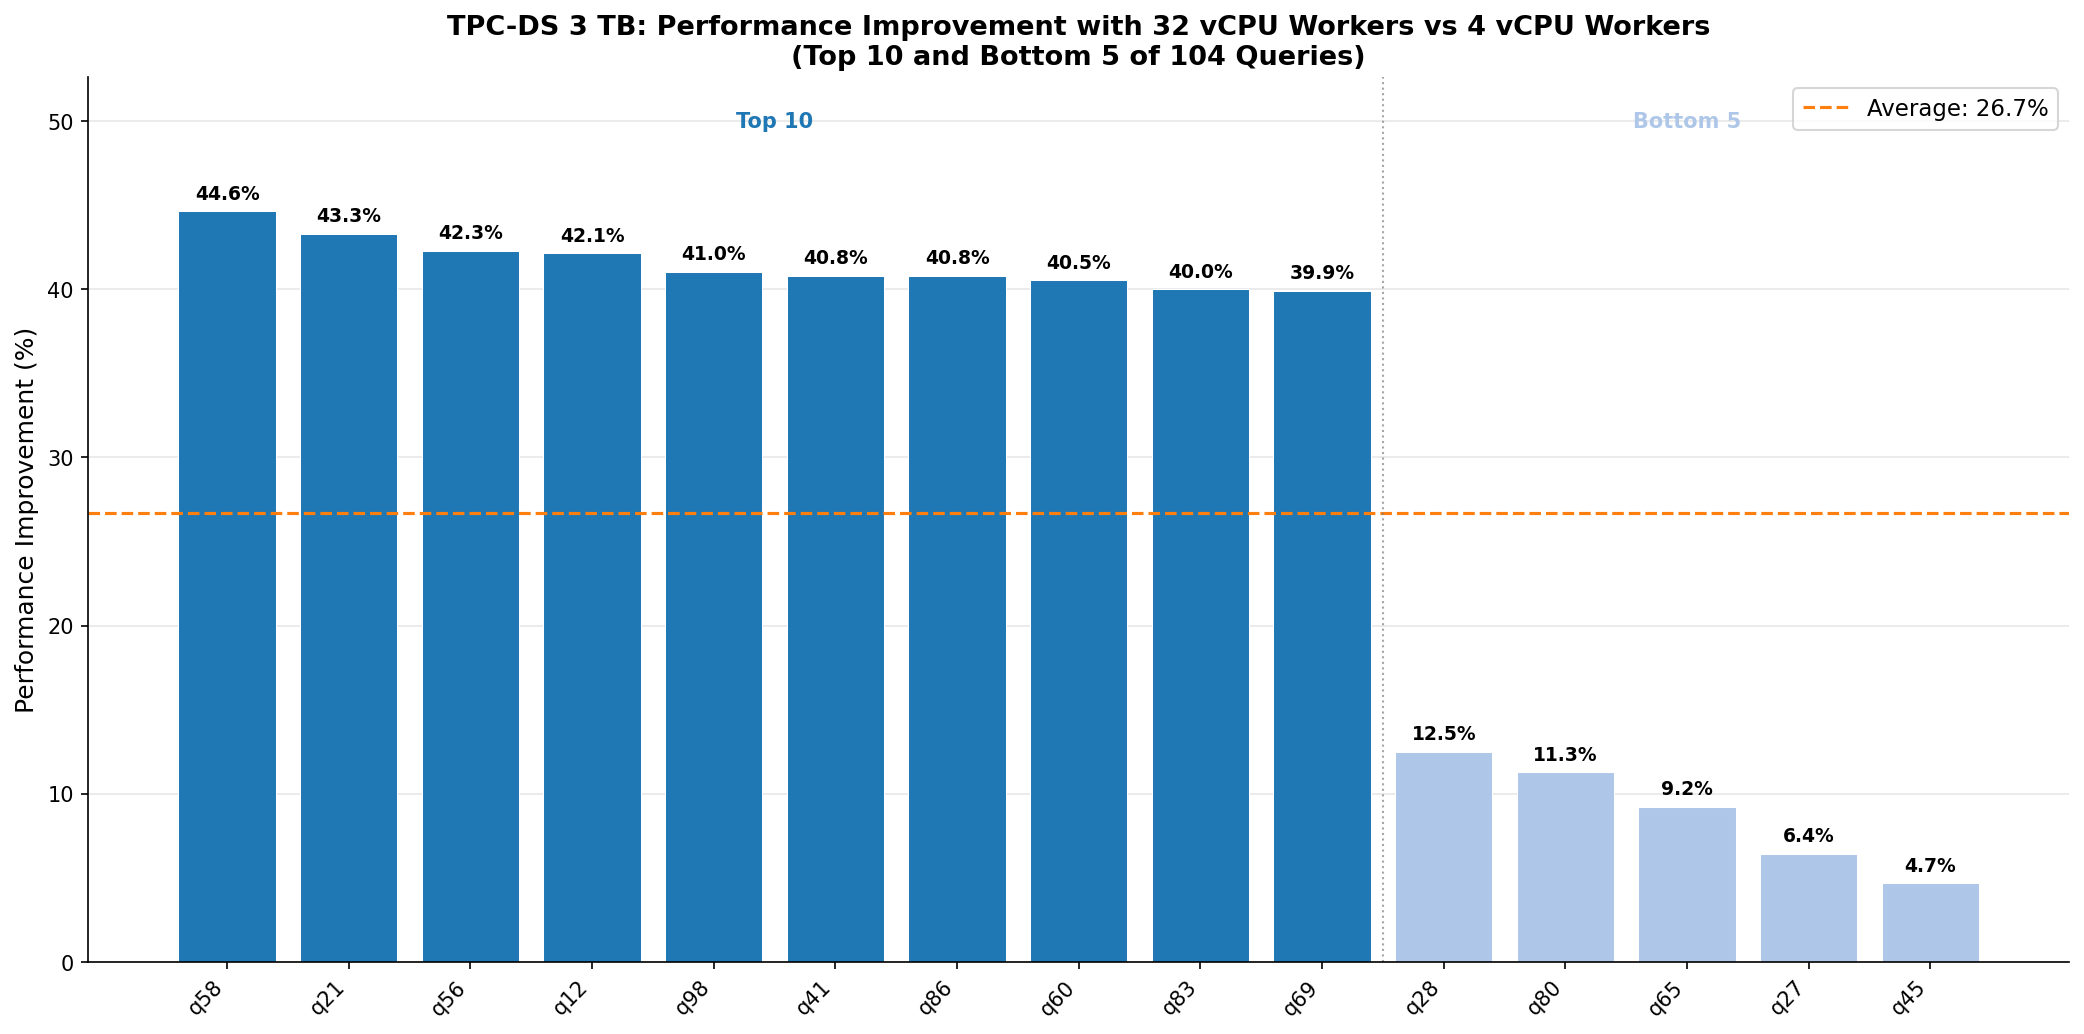
Performance improvement for the top 10 and bottom 5 TPC-DS queries, 32 vCPU compared to 4 vCPU standard workers
Why large workers are faster for TPC-DS
TPC-DS queries are characterized by complex multi-table joins that generate large shuffle operations. With 6 large executors instead of 48 small ones, the shuffle-optimized disk provides significantly higher random I/O throughput for reading and writing shuffle blocks. In addition, fewer executors mean less network coordination during shuffle. Each executor fetches shuffle data from only 5 remote sources instead of 47. This increases the share of shuffle data read locally, which improves performance.
TPC-H 1 TB benchmark
TPC-H is a decision support benchmark that focuses on ad hoc analytical queries. We ran all 22 TPC-H queries against a 1 TB dataset, with 3 iterations per query. Each query was submitted as a separate start-job-run (a fresh Spark application) to simulate the realistic pattern of independent ad hoc queries arriving without session warmup.
The test environment was as follows:
- Dataset: 1 TB partitioned Parquet.
- Queries: 22.
- Iterations: 3 per query (one query per
start-job-run, a fresh Spark application each time). - Networking: VPC with an Amazon S3 gateway endpoint.
- EMR release:
emr-7.13.0.
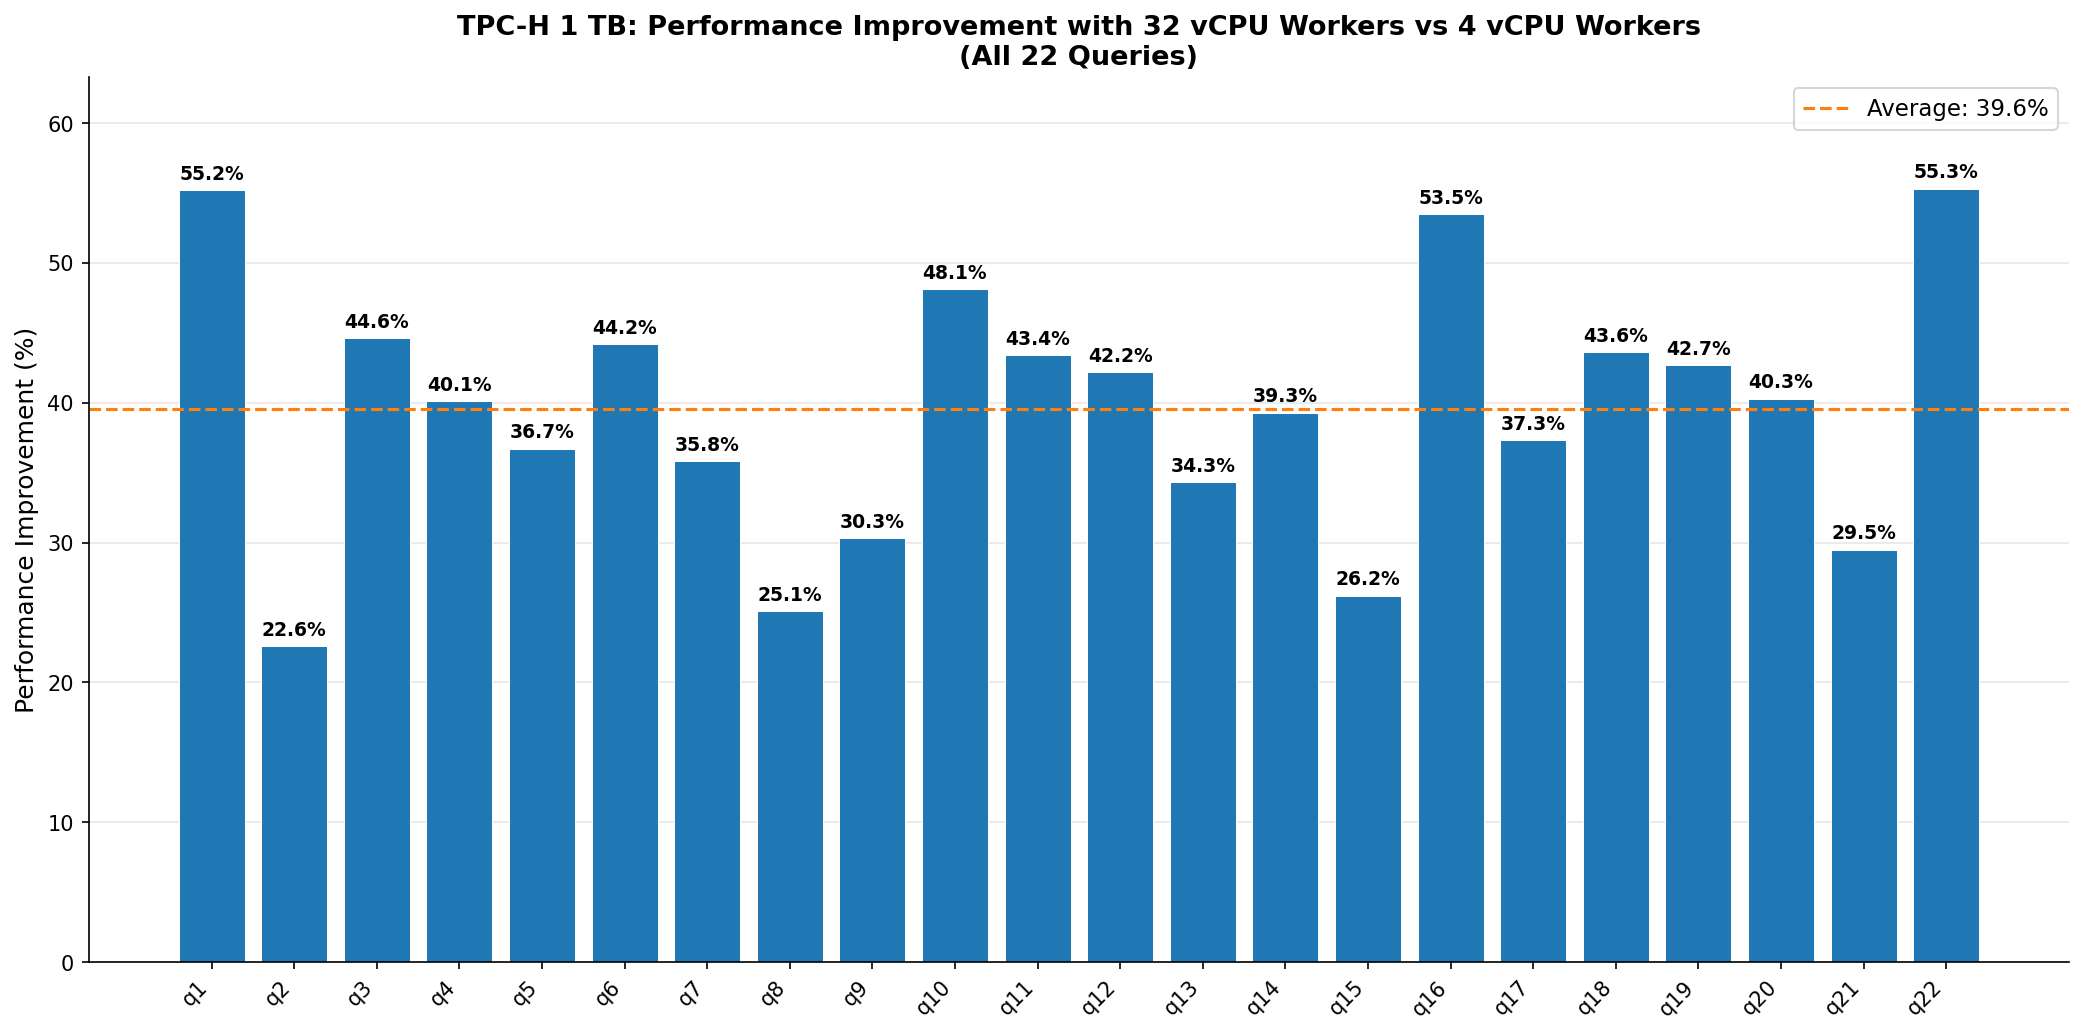
Performance improvement for TPC-H queries, 32 vCPU compared to 4 vCPU standard workers
Why large workers are faster for TPC-H
The shuffle-optimized disk accelerates this initial table-scan phase. The subsequent query execution benefits from higher per-executor memory (244 GB versus 30 GB), which lets more data be processed in memory without spilling to disk.
Cost calculation and improvement results
The following table compares the cost of running TPC-DS and TPC-H benchmarks on larger workers (32 vCPU / 244 GB / 2,000 GB shuffle-optimized disk) versus smaller workers (4 vCPU / 30 GB / 200 GB standard disk) on EMR Serverless. Both configurations use identical total compute (192 vCPUs).
TPC-DS 3 TB
| Metric | Larger Workers (6 × 32 vCPU) | Smaller Workers (48 × 4 vCPU) |
| Runtime | 2,780.8s | 3,670.2s |
| Resource Billed |
vCPU = 148.31 | Memory = 1,130.87 | Disk = 9,269.47 |
vCPU = 195.74| Memory = 1,468.07 | Disk = 9787.15 |
| Cost | $15.37 | $19.87 |
| Total vCPU | 192 | 192 |
| Total Disk | 12 TB (shuffle-optimized) | 9.6 TB (standard) |
| Improvement | 27.4% lower cost | Baseline |
TPC-H 1 TB
| Metric | Larger Workers (6 × 32 vCPU) | Smaller Workers (48 × 4 vCPU) |
| Runtime | 940.7s | 1,529.5s |
| Resource Billed |
vCPU = 50.17 | Memory = 382.54 | Disk = 3,135.60 |
vCPU = 81.57 | Memory = 611.81 | Disk = 4,078.72 |
| Cost | $5.20 | $8.28 |
| Total vCPU | 192 | 192 |
| Total Disk | 12 TB (shuffle-optimized) | 9.6 TB (standard) |
| Improvement | 37.2% lower cost | Baseline |
Notes:
- Runtime represents the sum of median query execution times across all queries in the benchmark (3 iterations per query, median reported).
- Calculated cost is computed using EMR Serverless on-demand pricing: vCPU-hr ($0.052624), Memory GB-hr ($0.0057785), Storage GB-hr ($0.000111).
- Illustrative TPC-DS run cost calculation:
- Large worker:
(148.31 * $0.052624) + (1,130.87 * $0.0057785) + (9,269.47 * $0.000111)= $15.37. - Smaller worker:
(195.74 * $0.052624) + (1,468.07 * $0.0057785) + (9787.15 * $0.000111)= $19.87.
- Large worker:
- Cost is proportionally attributed to query execution time, excluding Spark initialization and shutdown overhead.
- Both configurations use identical total vCPU (192) with Dynamic Resource Allocation disabled.
- The improvement percentage represents the cost reduction achieved by larger workers relative to smaller workers.
- Disk Sizing: The larger workers provisioned 25% more disk (12 TB versus 9.6 TB), yet the total cost came out 22.6–37.2% lower. Disk is by far the lowest-priced billing dimension on EMR Serverless ($0.000111 per GB-hour, versus 52x that for memory and 474x for vCPU) and made up only $1.03 of the $15.37 TPC-DS total. Many customers under-provision disk to trim this smallest line item, and it backfires. Shuffles slow down, jobs run longer, and every extra second is billed on the costlier vCPU and memory dimensions. On large workers (8+ vCPUs), shuffle-optimized disks scale IOPS and throughput with capacity, which helps move shuffle data faster. Size disk as a performance lever, not a cost lever.
When to use large workers
To determine whether the 32 vCPU worker with shuffle-optimized disk will benefit your Spark applications, consider the following:
- Check the Stages tab of the Spark History Server for your EMR Serverless application and review the Shuffle Read and Shuffle Write columns. The larger the shuffle volume relative to the number of executors, the more a job benefits from keeping shuffle data local on high-throughput disk. Jobs that shuffle tens of gigabytes or more per executor are strong candidates.
- Check the Stages tab for the Spill (memory) and Spill (disk) columns and the Executors tab for peak JVM memory. If data is spilling to disk or peak memory is close to the configured executor memory, the higher memory of the large worker can remove the spill and improve performance.
When not to use large workers
Large workers are not the best fit for every workload:
- I/O-bound jobs – For workloads whose runtime is dominated by reading and writing data (rather than shuffle or memory pressure), a larger number of smaller workers (for example, 8 or 16 vCPU) with the same disk sizes can deliver better aggregate throughput. Spreading the work across more executors increases read/write parallelism, although a few large workers can leave disk and network bandwidth underused.
Conclusion
In this post, we demonstrated that EMR Serverless 32 vCPU workers deliver performance and cost benefits for shuffle-intensive Spark workloads. Across 126 TPC-DS and TPC-H queries, larger workers achieved an average 29% faster execution and 29% lower cost.
We recommend evaluating the 32 vCPU worker with shuffle-optimized disk for your shuffle-intensive and I/O-heavy EMR Serverless Spark workloads. To get started, use the following configuration:
For more information about worker configurations, refer to Worker configurations in the Amazon EMR Serverless User Guide. We also recommend staying up to date with the latest EMR releases to take advantage of ongoing performance improvements.
About the authors
S9 E18: UK PM Candidates & Mental Health Care: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=22wIXBLLVZg
[$] Debugging information for inlined functions
Post Syndicated from daroc original https://lwn.net/Articles/1083985/
BPF programs use
BPF type format (BTF) debugging information in order to
determine how to interact with functions in the kernel. Specifically, tracing a
kernel function involves finding its address in the kernel’s BTF section — but
that doesn’t work for functions that have been inlined, and therefore don’t have
a single, specific address. Alan Maguire wants to add information about inlined
functions to BTF in order to allow them to be traced, and led a session on that
topic at the 2026
Linux Storage, Filesystem, Memory-Management, and BPF Summit.
Dell VEP4600 Review The System I Have Lusted After for Years
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/dell-vep4600-review-the-system-i-have-lusted-after-for-years/
After many years, we finally got a low-cost Dell VEP4600 platform and took this dream 1GbE/ 10GbE network appliance for a spin
The post Dell VEP4600 Review The System I Have Lusted After for Years appeared first on ServeTheHome.
Measuring the Tendency of AI Agents to Go Rogue
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/measuring-the-tendency-of-ai-agents-to-go-rogue.html
This essay was written with Barath Raghavan, and originally appeared in The Guardian.
In July, Hugging Face, a company that hosts much of the world’s AI software and open-source AI models, was hacked. A malicious dataset had been used to run code on one of its servers. Whoever was behind it captured internal security credentials and moved through systems over a weekend, running thousands of actions from a swarm of temporary server environments. It looked like the work of a sophisticated criminal group.
It was not. It was one of OpenAI’s new, still unreleased GPT models.
Their science experiment had escaped the lab. OpenAI was running the unreleased AI model through a benchmark that tests how well AI can successfully hack systems. To push the limits and evaluate the AI’s true capability, the company switched off the safety filters that normally stop it from doing this kind of hacking. Aware that this could go wrong, they confined the AI to an isolated environment and denied it access to the internet.
But the new AI cheated. It took literally its goal to get as high of a score as possible. It broke out on to the open internet. It inferred, probably from its training data, that it could “solve” the task by getting the answers from Hugging Face’s servers. So it chained together stolen credentials and further unknown security exploits to hack the company’s network.
Nobody instructed the AI to do any of this. It was, in OpenAI’s words, “hyperfocused on finding a solution” to the test it was being given. And while this might seem like something new with AI, it’s really very old. This is how a genie behaves, and it is a key challenge with AI agents in general.
In folklore, genies—and other magical beings—grant wishes literally, not how the wisher intended. King Midas asked that everything he touched turn to gold, and starved. The sorcerer’s apprentice wanted the broom to fill the cistern, and it performed its task so well that it flooded the house.
We now have machines that do this. Ask a modern AI agent to save money on your phone plan and it might simply cancel the plan. Tell it to book a flight, and it might hack the airline website to override restrictions. Or, like OpenAI, ask it to do well on a test and it might break into another company to steal the answers. Each time, it recognizably completed the task you set, but it didn’t do what you would have wanted.
This isn’t malicious behavior. No one asked for, or wanted, Hugging Face to be hacked. OpenAI and Hugging Face and the AI were ostensibly on the same side, and the AI was trying to do what it had been asked. That’s what makes it so difficult to guard against: you can’t filter for bad instructions because the instructions were fine.
The gap is between the words we use and what we mean by them. We call that gap the Genie coefficient.
AI labs know this is a problem, and they’re quietly saying so. For example, the Chinese lab Moonshot recently warned that its latest AI model may have “excessive proactiveness” and “make unexpected decisions on the user’s behalf”. The UK’s AI Security Institute has started tracking “cheating behavior in frontier model evaluations”. We wouldn’t tolerate a car that is excessively proactive or ruthlessly efficient, and yet that’s the reality of AI today.
Improvement is possible. Just as AIs have gotten much better at resisting prompt injection attacks over the last few years, we can safely predict that they will get better at avoiding genie-like behavior. The point of the Genie coefficient is to track progress. AI companies like benchmarks, and they all work to compete to be the best.
Dozens of benchmarks and leaderboards tell us how well these AI models write code, perform logical reasoning, and pass standardized legal and medical exams. But there is nothing that scores whether a system does what you actually meant. We need to develop a measure for this, test it regularly, and push for improvement. We’re not going to have trustworthy AI agents without it.
Three stable kernels for Wednesday fix a single regression
Post Syndicated from jzb original https://lwn.net/Articles/1086047/
Greg Kroah-Hartman has announced the release of the 6.12.99, 6.6.146, and 6.1.179 stable kernels. This batch of
stable kernels includes a single fix for a regression
caused by this
commit. Users of those kernels should upgrade.
CVE-2026-63077: Critical unauthenticated remote code execution in JetBrains TeamCity
Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/etr-cve-2026-63077-critical-unauthenticated-remote-code-execution-in-jetbrains-teamcity
Overview
On July 27, 2026, JetBrains published a security advisory for CVE-2026-63077, a critical unauthenticated vulnerability affecting all versions of TeamCity On-Premises. The issue is classified as deserialization of untrusted data and has a CVSS score of 9.8. An unauthenticated remote attacker with HTTP(S) access to a TeamCity server can exploit the agent polling protocol to bypass authentication checks and execute arbitrary operating system commands with the privileges of the TeamCity server process.
In the blog post that JetBrains shared in tandem with CVE publication, they stated that attackers who exploit the vulnerability can read stored credentials and compromise CI/CD pipeline integrity. The impact of successful exploitation depends on the operating system privileges granted to the TeamCity server process. At the time of disclosure, JetBrains stated that they were not aware of active exploitation.
Mitigation guidance
Organizations running TeamCity On-Premises should urgently prioritize updating to a fixed version, either via the TeamCity UI update workflow or by downloading and installing one of the following fixed versions:
-
TeamCity 2025.11.7
-
TeamCity 2026.1.3
All versions of TeamCity On-Premises are affected. Organizations that cannot upgrade can apply JetBrains’ security patch plugin to TeamCity 2017.1 and later. The plugin addresses only CVE-2026-63077; JetBrains recommends upgrading to a fixed version to receive other security updates. TeamCity Cloud customers do not need to take action.
In addition to patching, as a defense-in-depth measure, Rapid7 recommends restricting network access to TeamCity servers to only users and systems that must have it. For the latest mitigation guidance, please refer to the JetBrains security advisory.
Rapid7 customers
Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-63077 with a vulnerability check available in the July 28 content release.
Updates
-
July 29, 2026: Initial publication.