Tag Archives: announcements

Over 40 services require TLS 1.2 minimum for AWS FIPS endpoints

Post Syndicated from Janelle Hopper original https://aws.amazon.com/blogs/security/over-40-services-require-tls-1-2-minimum-for-aws-fips-endpoints/

In a March 2020 blog post, we told you about work Amazon Web Services (AWS) was undertaking to update all of our AWS Federal Information Processing Standard (FIPS) endpoints to a minimum of Transport Layer Security (TLS) 1.2 across all AWS Regions. Today, we’re happy to announce that over 40 services have been updated and now require TLS 1.2:

These services no longer support using TLS 1.0 or TLS 1.1 on their FIPS endpoints. To help you meet your compliance needs, we are updating all AWS FIPS endpoints to a minimum of TLS 1.2 across all Regions. We will continue to update our services to support only TLS 1.2 or later on AWS FIPS endpoints, which you can check on the AWS FIPS webpage. This change doesn’t affect non-FIPS AWS endpoints.

When you make a connection from your client application to an AWS service endpoint, the client provides its TLS minimum and TLS maximum versions. The AWS service endpoint will always select the maximum version offered.

What is TLS?

TLS is a cryptographic protocol designed to provide secure communication across a computer network. API calls to AWS services are secured using TLS.

What is FIPS 140-2?

The FIPS 140-2 is a US and Canadian government standard that specifies the security requirements for cryptographic modules that protect sensitive information.

What are AWS FIPS endpoints?

All AWS services offer TLS 1.2 encrypted endpoints that can be used for all API calls. Some AWS services also offer FIPS 140-2 endpoints for customers who need to use FIPS validated cryptographic libraries to connect to AWS services.

Why are we upgrading to TLS 1.2?

Our upgrade to TLS 1.2 across all Regions reflects our ongoing commitment to help customers meet their compliance needs.

Is there more assistance available to help verify or update client applications?

If you’re using an AWS software development kit (AWS SDK), you can find information about how to properly configure the minimum and maximum TLS versions for your clients in the following AWS SDK topics:

You can also visit Tools to Build on AWS and browse by programming language to find the relevant SDK. AWS Support tiers cover development and production issues for AWS products and services, along with other key stack components. AWS Support doesn’t include code development for client applications.

If you have any questions or issues, you can start a new thread on one of the AWS forums, or contact AWS Support or your technical account manager (TAM).

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Janelle Hopper

Janelle Hopper is a Senior Technical Program Manager in AWS Security with over 15 years of experience in the IT security field. She works with AWS services, infrastructure, and administrative teams to identify and drive innovative solutions that improve AWS’ security posture.

Author

Marta Taggart

Marta is a Seattle-native and Senior Program Manager in AWS Security, where she focuses on privacy, content development, and educational programs. Her interest in education stems from two years she spent in the education sector while serving in the Peace Corps in Romania. In her free time, she’s on a global hunt for the perfect cup of coffee.

Verified episode 3: In conversation with Noopur Davis from Comcast

Post Syndicated from Stephen Schmidt original https://aws.amazon.com/blogs/security/verified-episode-3-in-conversation-with-noopur-davis-from-comcast/

2020 emphasized the value of staying connected with our customers. On that front, I’m proud to bring you the third episode of our new video series, Verified. The series showcases conversations with security leaders discussing trends and lessons learned in cybersecurity, privacy, and the cloud. In episode three, I’m talking to Noopur Davis, Executive Vice President and Chief Product and Information Security Officer at Comcast. As you can imagine, she had a busy 2020, as Comcast owns and operates Comcast Business and Xfinity, among others. During our conversation, we spoke about Comcast’s commitment to proactive security, with leaders setting a high bar for technology and decision-making.

Additionally, Noopur shared her journey in becoming a security leader at Comcast, talking about career growth, creating a security culture, diversity and inclusion, and measuring impact. During our conversation, she also detailed the importance of embedding security into the development lifecycle: “At Comcast, we stood up a Cloud Center of Excellence that included network engineering, security engineering and cloud engineering as equal partners. We came together to ensure we had the governance, technology, implementation, and rollout set up. Through this collaboration, everything came together. Collaboration is how this happens—the security team has to be embedded with other key technology teams.”

Noopur also recognized the heroic efforts of Comcast’s team responsible for security and increasing network bandwidth to meet the new work-from-home realities introduced by the pandemic. These efforts included dramatically accelerating timelines to meet pace of demand. “The network has never been more important. People are now doing everything over the network. I’m so proud to say that all the investment over the years that Comcast made in the network has stood up to this new reality. We added 35 terabits per second of capacity to get ready for increased demand. Our frontline people that did this work during the pandemic are really the heroes of Comcast. We also had programs underway that were accelerated by months. We did things in weeks that weren’t planned to be done for months.”

Stay tuned for future episodes of Verified here on the AWS Security Blog. You can watch episode one, an interview with Jason Chan, Vice President of Information Security at Netflix and episode two, an interview with Emma Smith, Vodafone’s Global Cybersecurity Director, on YouTube. If you have an idea or a topic you’d like covered in this series, please drop us a comment below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Steve Schmidt

Steve is Vice President and Chief Information Security Officer for AWS. His duties include leading product design, management, and engineering development efforts focused on bringing the competitive, economic, and security benefits of cloud computing to business and government customers. Prior to AWS, he had an extensive career at the Federal Bureau of Investigation, where he served as a senior executive and section chief. He currently holds 11 patents in the field of cloud security architecture. Follow Steve on Twitter.

New – Multiple Private Marketplace Catalogs

Post Syndicated from Martin Beeby original https://aws.amazon.com/blogs/aws/new-multiple-private-marketplace-catalogs/

We launched AWS Marketplace in 2014, and it allows customers to find, buy, and immediately start using cloud-based applications developed by independent software vendors (ISVs). In 2018, we added the ability to add a Private Marketplace where you can curate a list of approved products your users can purchase from AWS Marketplace. Today we are adding a new feature so that you can create multiple Private Marketplace catalogs within your AWS Organizations. Each Private Marketplace can contain a different set of products to provide a tailored experience for particular groups of accounts.

Customers with diverse sets of users need to scale their governance to meet business needs. For example, a large enterprise with subsidiaries in different industries has varying software needs and policies for each subsidiary. IT administrators struggle with scaling their procurement process to address these differing needs across their organization and often revert to one procurement policy to govern their entire org. While there are exceptions, companies depend on time-consuming, manual processes to ensure the correct products are approved and procured. As a result, customers struggle to scale their procurement and governance process to meet their organization’s speed and agility demands.

After listening to customers explain these sorts of issues, we set about developing a solution to help, and the concept of multiple Private Marketplace catalogs was born. We call these Private Marketplace experiences. They represent the experience that your users will see when they browse their AWS Marketplace. Each experience is a collection of approved AWS Marketplace products that you, as an administrator, select and curate. You can add any of the 8000-plus products from AWS Marketplace to an experience and customize the look and feel by changing the Private Marketplace logo, wording, and color.

In the Private Marketplace admin portal, within the AWS Marketplace interface, you can create an Account group, which is essentially a way of grouping together a number of AWS accounts. You can then associate an experience with an Account group, enabling you to give different users distinct experiences. This association allows you to govern the use of third-party software subscriptions and ensure they adhere to your internal procurement policies.

To give you a flavor of this feature, I will create a new Private Marketplace experience.

How to Create a Private Marketplace Experience
I head over to the Private Marketplace interface and select the Experiences link; this lists the default experience called Private Marketplace Experience. I then press the Create experience button.

I give the experience a name and a description and click the Create experience button.

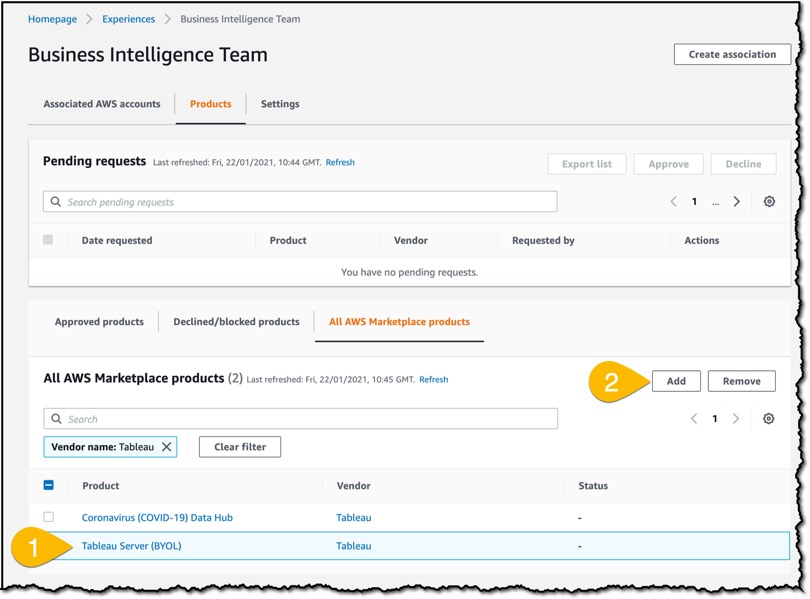
If I drill into the details for my newly created experience, I can then start to add products to my catalog. I use the search in the All AWS Marketplace products section and look for Tableau. I find the Tableau Server product and select it. I then click the Add button which adds the product to my catalog.

Screenshot, adding a product

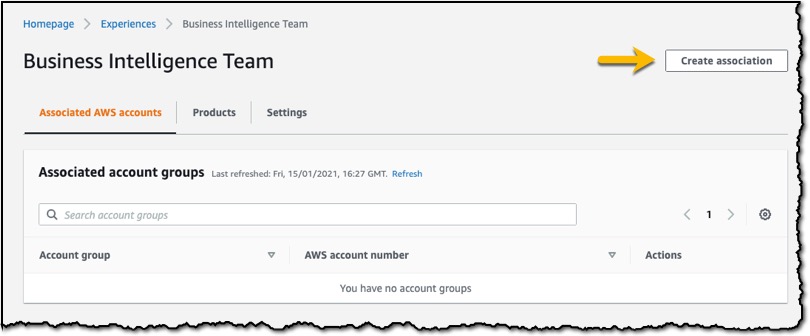
To associate this experience with a set of AWS accounts, I click on the Create association button; this allows me to create a new Account group.

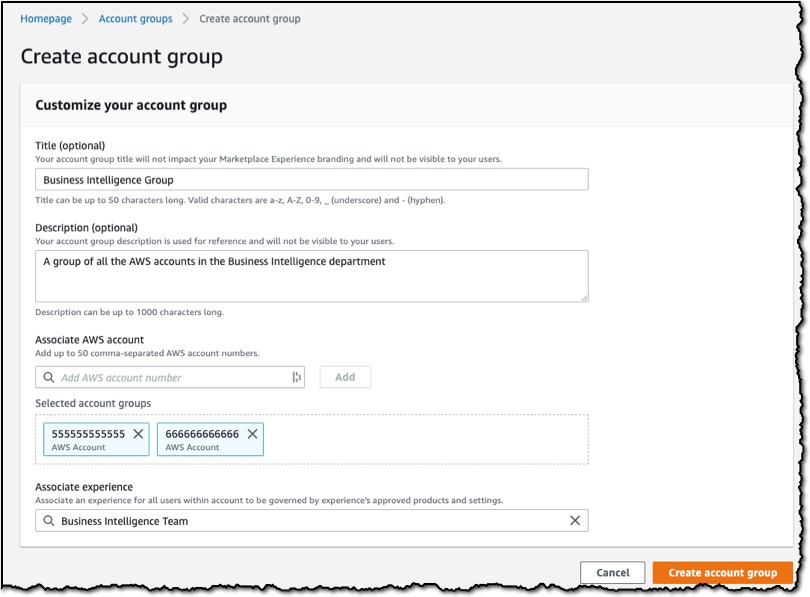
I give my account group the title Business Intelligence Group and add a description. I then associate AWS accounts that I want to be part of this group. Finally, I associate this group with the Business Intelligence Team experience I created earlier and finally click Create account group.

I now go to the settings for the experience and change the switch so that the experience is now live. On this screen I can also customize the look and feel of the Private Marketplace by uploading a logo, changing the color, and adding custom wording.

Now, if I log in and browse the AWS Marketplace using an account that is in the Account group I just created, I will see the Private Marketplace experience rather than the regular AWS Marketplace.

Available now
The ability to create multiple Private Marketplace catalogs is available now in all regions that support AWS Marketplace, and you can start using the feature directly from the Private Marketplace interface. Additionally, you can use the accompanying set of APIs so that you can integrate with existing approval or ticketing systems to simplify management across catalogs.

Visit the Private Marketplace page to get started and learn more. Happy curating.

— Martin

Understanding memory usage in your Java application with Amazon CodeGuru Profiler

Post Syndicated from Fernando Ciciliati original https://aws.amazon.com/blogs/devops/understanding-memory-usage-in-your-java-application-with-amazon-codeguru-profiler/

“Where has all that free memory gone?” This is the question we ask ourselves every time our application emits that dreaded OutOfMemoyError just before it crashes. Amazon CodeGuru Profiler can help you find the answer.

Thanks to its brand-new memory profiling capabilities, troubleshooting and resolving memory issues in Java applications (or almost anything that runs on the JVM) is much easier. AWS launched the CodeGuru Profiler Heap Summary feature at re:Invent 2020. This is the first step in helping us, developers, understand what our software is doing with all that memory it uses.

The Heap Summary view shows a list of Java classes and data types present in the Java Virtual Machine heap, alongside the amount of memory they’re retaining and the number of instances they represent. The following screenshot shows an example of this view.

Amazon CodeGuru Profiler heap summary view example

Figure: Amazon CodeGuru Profiler Heap Summary feature

Because CodeGuru Profiler is a low-overhead, production profiling service designed to be always on, it can capture and represent how memory utilization varies over time, providing helpful visual hints about the object types and the data types that exhibit a growing trend in memory consumption.

In the preceding screenshot, we can see that several lines on the graph are trending upwards:

  • The red top line, horizontal and flat, shows how much memory has been reserved as heap space in the JVM. In this case, we see a heap size of 512 MB, which can usually be configured in the JVM with command line parameters like -Xmx.
  • The second line from the top, blue, represents the total memory in use in the heap, independent of their type.
  • The third, fourth, and fifth lines show how much memory space each specific type has been using historically in the heap. We can easily spot that java.util.LinkedHashMap$Entry and java.lang.UUID display growing trends, whereas byte[] has a flat line and seems stable in memory usage.

Types that exhibit constantly growing trend of memory utilization with time deserve a closer look. Profiler helps you focus your attention on these cases. Associating the information presented by the Profiler with your own knowledge of your application and code base, you can evaluate whether the amount of memory being used for a specific data type can be considered normal, or if it might be a memory leak – the unintentional holding of memory by an application due to the failure in freeing-up unused objects. In our example above, java.util.LinkedHashMap$Entry and java.lang.UUIDare good candidates for investigation.

To make this functionality available to customers, CodeGuru Profiler uses the power of Java Flight Recorder (JFR), which is now openly available with Java 8 (since OpenJDK release 262) and above. The Amazon CodeGuru Profiler agent for Java, which already does an awesome job capturing data about CPU utilization, has been extended to periodically collect memory retention metrics from JFR and submit them for processing and visualization via Amazon CodeGuru Profiler. Thanks to its high stability and low overhead, the Profiler agent can be safely deployed to services in production, because it is exactly there, under real workloads, that really interesting memory issues are most likely to show up.

Summary

For more information about CodeGuru Profiler and other AI-powered services in the Amazon CodeGuru family, see Amazon CodeGuru. If you haven’t tried the CodeGuru Profiler yet, start your 90-day free trial right now and understand why continuous profiling is becoming a must-have in every production environment. For Amazon CodeGuru customers who are already enjoying the benefits of always-on profiling, this new feature is available at no extra cost. Just update your Profiler agent to version 1.1.0 or newer, and enable Heap Summary in your agent configuration.


Happy profiling!

AWS is the first global cloud service provider to comply with the new K-ISMS-P standard

Post Syndicated from Seulun Sung original https://aws.amazon.com/blogs/security/aws-is-the-first-global-cloud-service-provider-to-comply-with-the-new-k-isms-p-standard/

We’re excited to announce that Amazon Web Services (AWS) has achieved certification under the Korea-Personal Information & Information Security Management System (K-ISMS-P) standard (effective from December 16, 2020 to December 15, 2023). The assessment by the Korea Internet & Security Agency (KISA) covered the operation of infrastructure (including compute, storage, networking, databases, and security) in the AWS Asia Pacific (Seoul) Region. AWS was the first global cloud service provider (CSP) to obtain K-ISMS certification (the previous version of K-ISMS-P) back in 2017. Now AWS is the first global CSP to achieve compliance with the K-ISMS portion of the new K-ISMS-P standard.

Sponsored by KISA and affiliated with the Korean Ministry of Science and ICT (MSIT), K-ISMS-P serves as a standard for evaluating whether enterprises and organizations operate and manage their information security management systems consistently and securely, such that they thoroughly protect their information assets. The new K-ISMS-P standard combined the K-ISMS and K-PIMS (Personal Information Management System) standards with updated control items. Accordingly, the new K-ISMS certification and K-ISMS-P certification (personal information–focused) are introduced under the updated standard.

In this year’s audit, 110 services running in the Asia Pacific (Seoul) Region are included. The newly launched Availability Zone in 2020 is also added to the certification scope.

This certification helps enterprises and organizations across South Korea, regardless of industry, meet KISA compliance requirements more efficiently. Achieving this certification demonstrates the proactive approach AWS has taken to meet compliance set by the South Korean government and to deliver secure AWS services to customers. In addition, we’ve launched Quick Start and Operational Best Practices (conformance pack) pages to provide customers with a compliance framework that they can utilize for their K-ISMS-P compliance needs. Enterprises and organizations can use these toolkits and AWS certification to reduce the effort and cost of getting their own K-ISMS-P certification. You can download the AWS K-ISMS certification under the K-ISMS-P standard from AWS Artifact. To learn more about the AWS K-ISMS certification, see the AWS K-ISMS page. If you have any questions, don’t hesitate to contact your AWS Account Manager.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Seulun Sung

Seulun is a Security Audit Program Manager at AWS, leading security certification programs, with a focus on the K-ISMS-P program in South Korea. She has a decade of experience in deploying global policies and processes to local Regions and helping customers adopt regulations. She is passionate about helping to build customers’ trust and provide them assurance on cloud security.

Amazon Lex Introduces an Enhanced Console Experience and New V2 APIs

Post Syndicated from Martin Beeby original https://aws.amazon.com/blogs/aws/amazon-lex-enhanced-console-experience/

Today, the Amazon Lex team has released a new console experience that makes it easier to build, deploy, and manage conversational experiences. Along with the new console, we have also introduced new V2 APIs, including continuous streaming capability. These improvements allow you to reach new audiences, have more natural conversations, and develop and iterate faster.

The new Lex console and V2 APIs make it easier to build and manage bots focusing on three main benefits. First, you can add a new language to a bot at any time and manage all the languages through the lifecycle of design, test, and deployment as a single resource. The new console experience allows you to quickly move between different languages to compare and refine your conversations. I’ll demonstrate later how easy it was to add French to my English bot.

Second, V2 APIs simplify versioning. The new Lex console and V2 APIs provide a simple information architecture where the bot intents and slot types are scoped to a specific language. Versioning is performed at the bot level so that resources such as intents and slot types do not have to be versioned individually. All resources within the bot (language, intents, and slot types) are archived as part of the bot version creation. This new way of working makes it easier to manage bots.

Lastly, you have additional builder productivity tools and capabilities to give you more flexibility and control of your bot design process. You can now save partially completed work as you develop different bot elements as you script, test and tune your configuration. This provides you with more flexibility as you iterate through the bot development. For example, you can save a slot that refers to a deleted slot type. In addition to saving partially completed work, you can quickly navigate across the configuration without getting lost. The new Conversation flow capability allows you to maintain your orientation as you move across the different intents and slot types.

In addition to the enhanced console and APIs, we are providing a new streaming conversation API. Natural conversations are punctuated with pauses and interruptions. For example, a customer may ask to pause the conversation or hold the line while looking up the necessary information before answering a question to retrieve credit card details when providing bill payments. With streaming conversation APIs, you can pause a conversation and handle interruptions directly as you configure the bot. Overall, the design and implementation of the conversation is simplified and easy to manage. The bot builder can quickly enhance the conversational capability of virtual contact center agents or smart assistants.

Let’s create a new bot and explore how some of Lex’s new console and streaming API features provide an improved bot building experience.

Building a bot
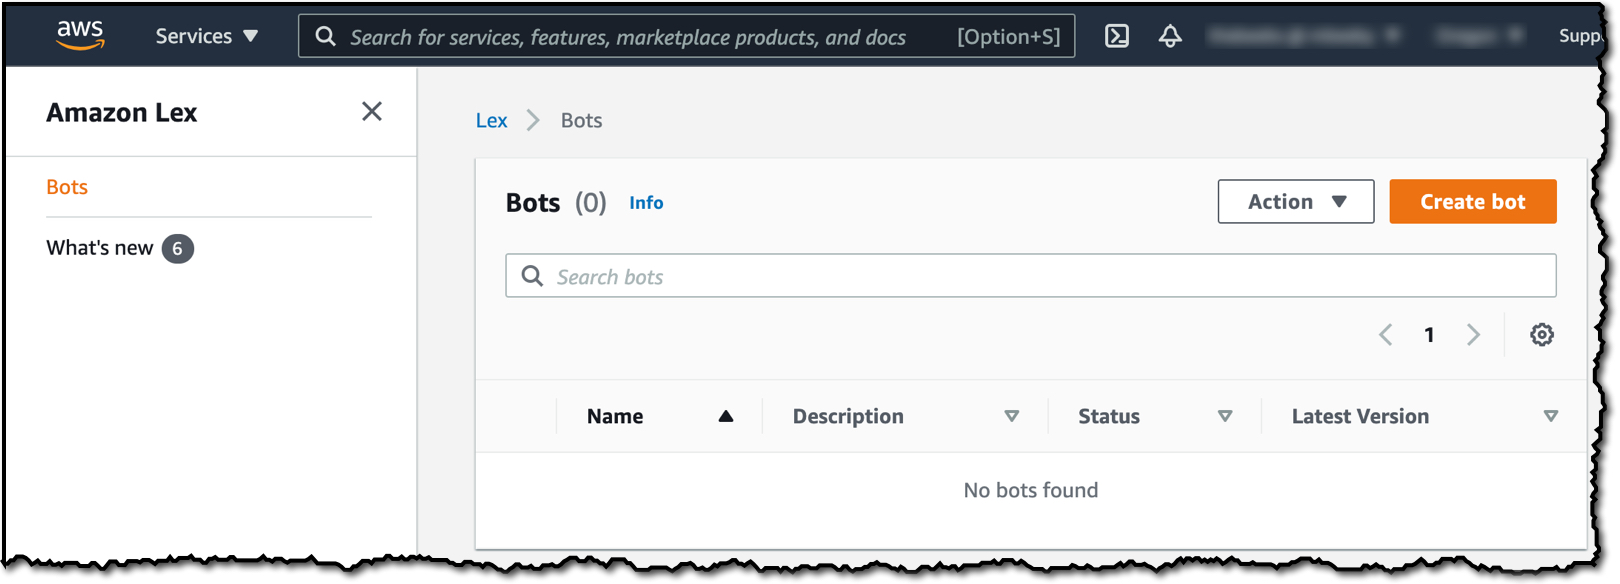
I head over to the new V2 Lex console and click on Create bot to start things off.

I select that I want to Start with an example and select the MakeAppointment example.

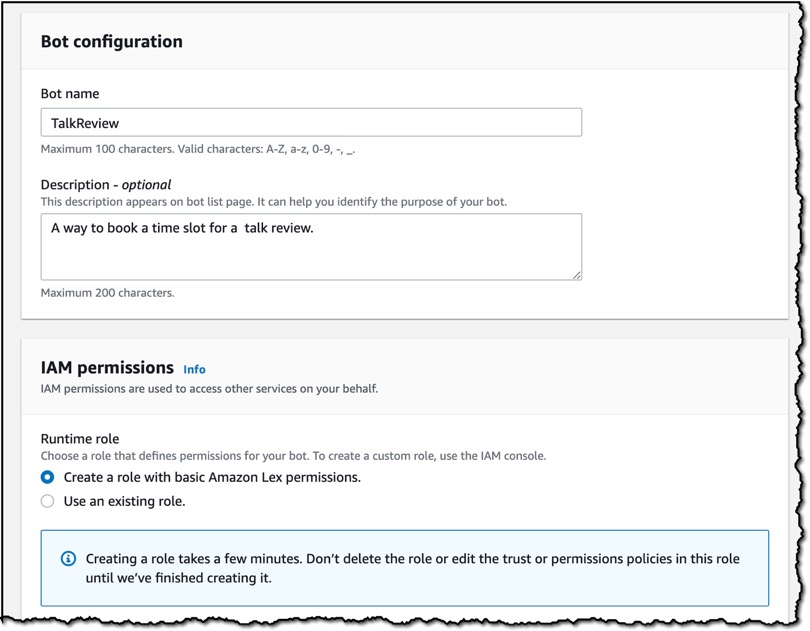
Over the years, I have spoken at many conferences, so I now offer to review talks that other community members are producing. Since these speakers are often in different time zones, it can be complicated to organize the various appointments for the different types of reviews that I offer. So I have decided to build a bot to streamline the process. I give my bot the name TalkReview and provide a description. I also select Create a role with basic Amazon Lex permissions and use this as my runtime role.

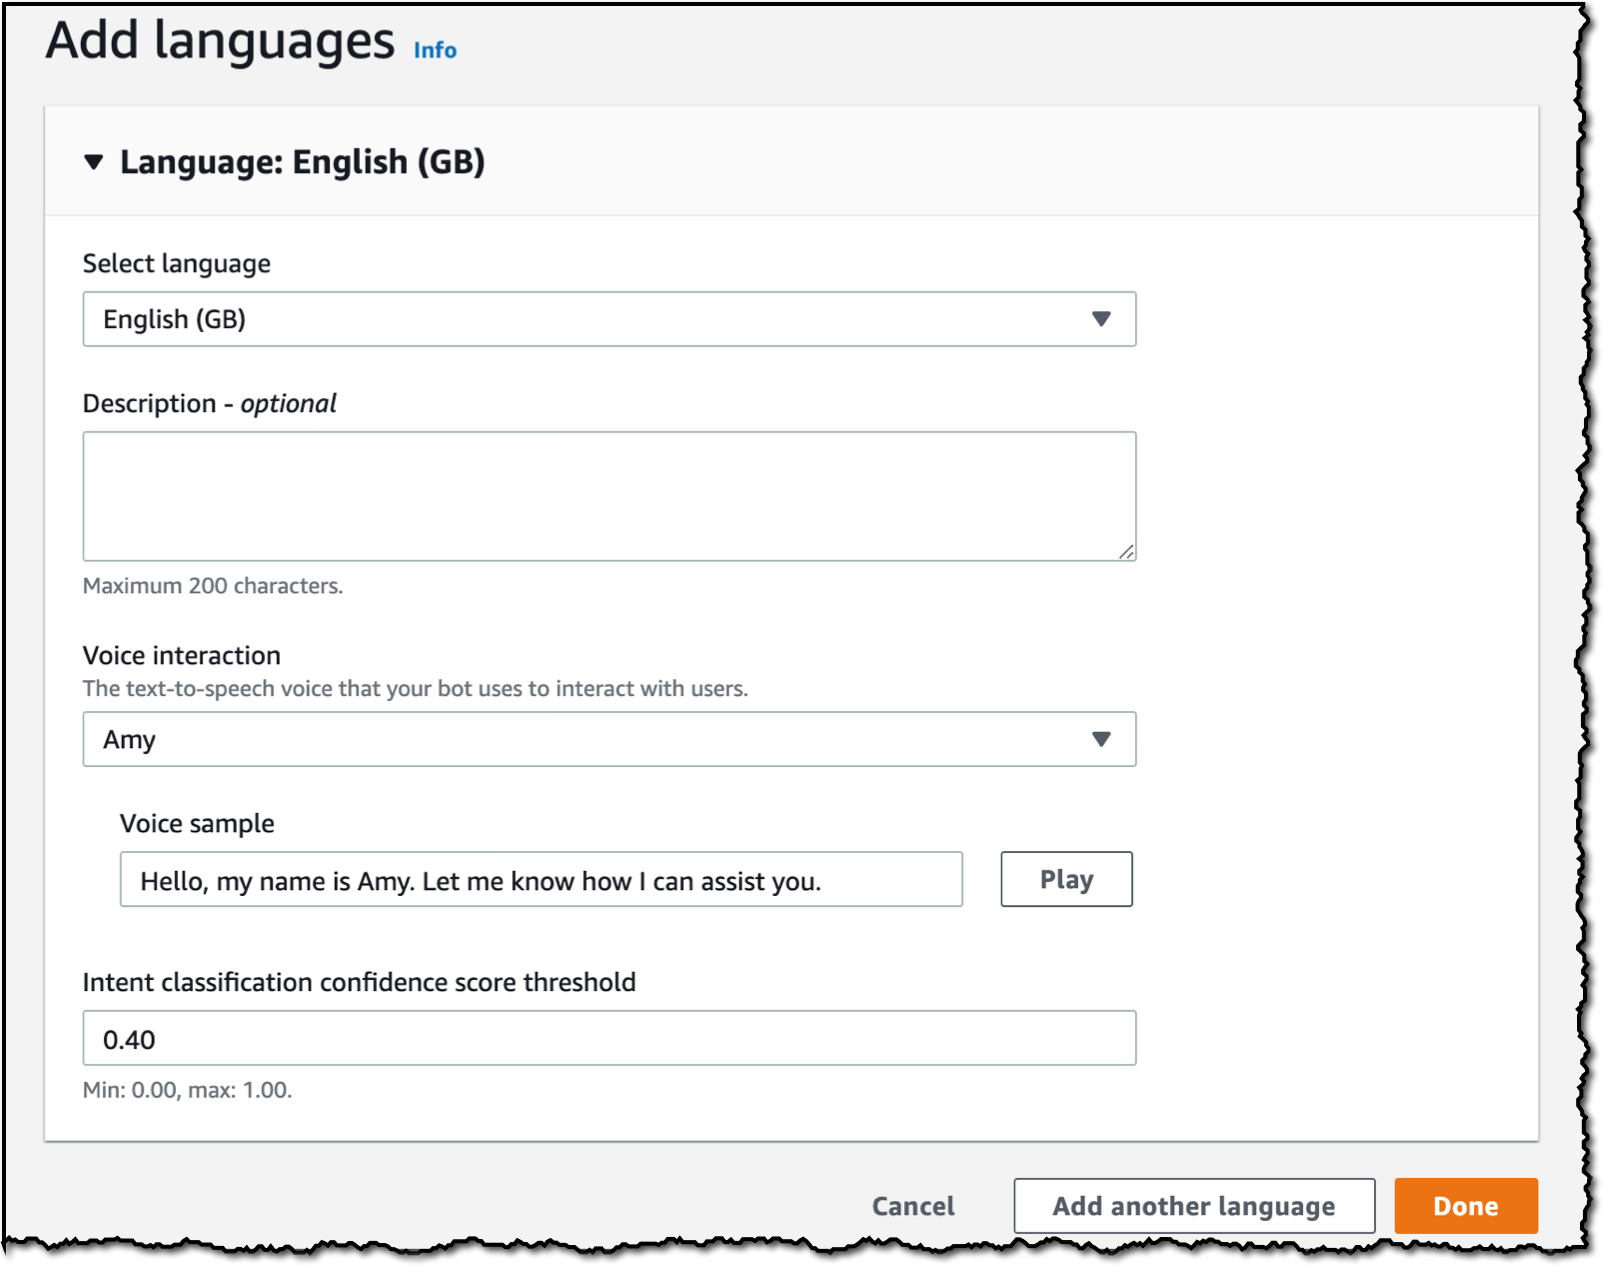
I must add at least one language to my bot, so I start with English (GB). I also select the text-to-speech voice that I want to use should my bot require voice interaction rather than just text.

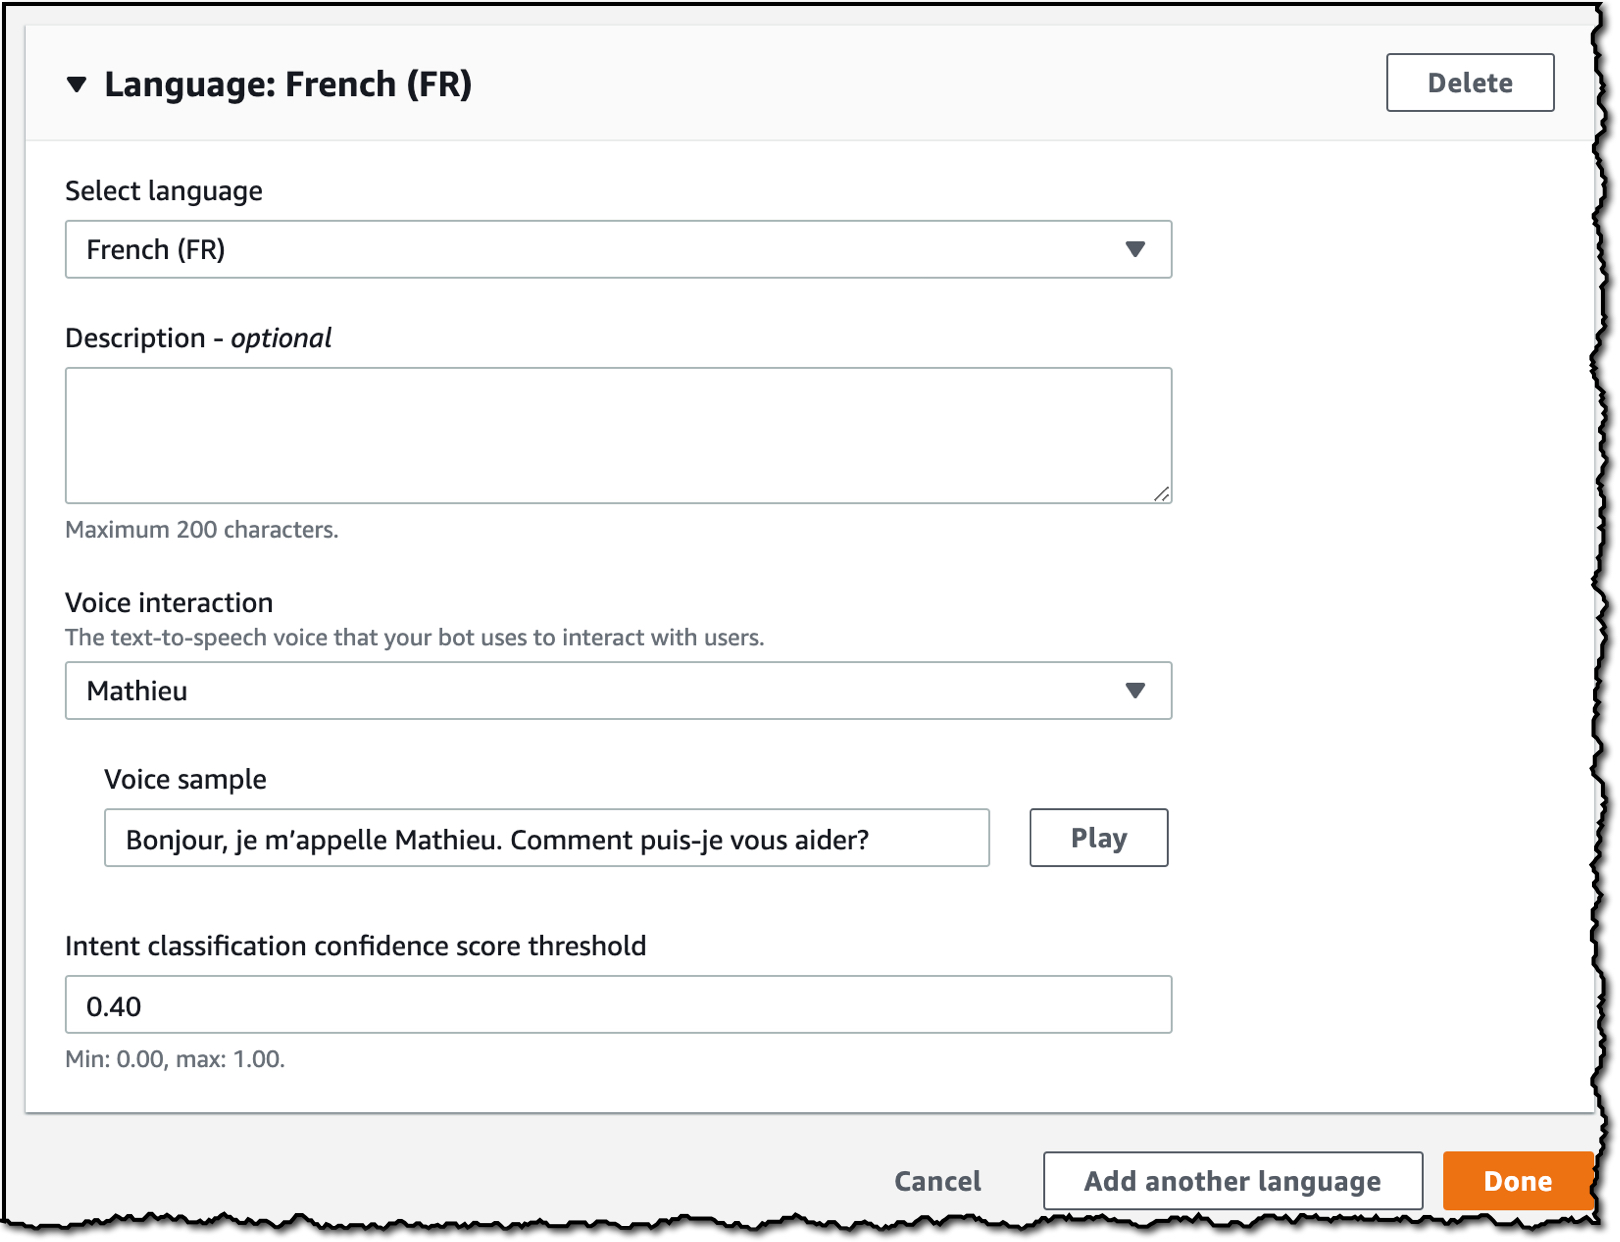
During the creation, there is a new button that allows me to Add another language. I click on this to add French (FR) to my bot. You can add languages during creation as I am doing here, or you can add additional languages later on as your bot becomes more popular and needs to work with new audiences.

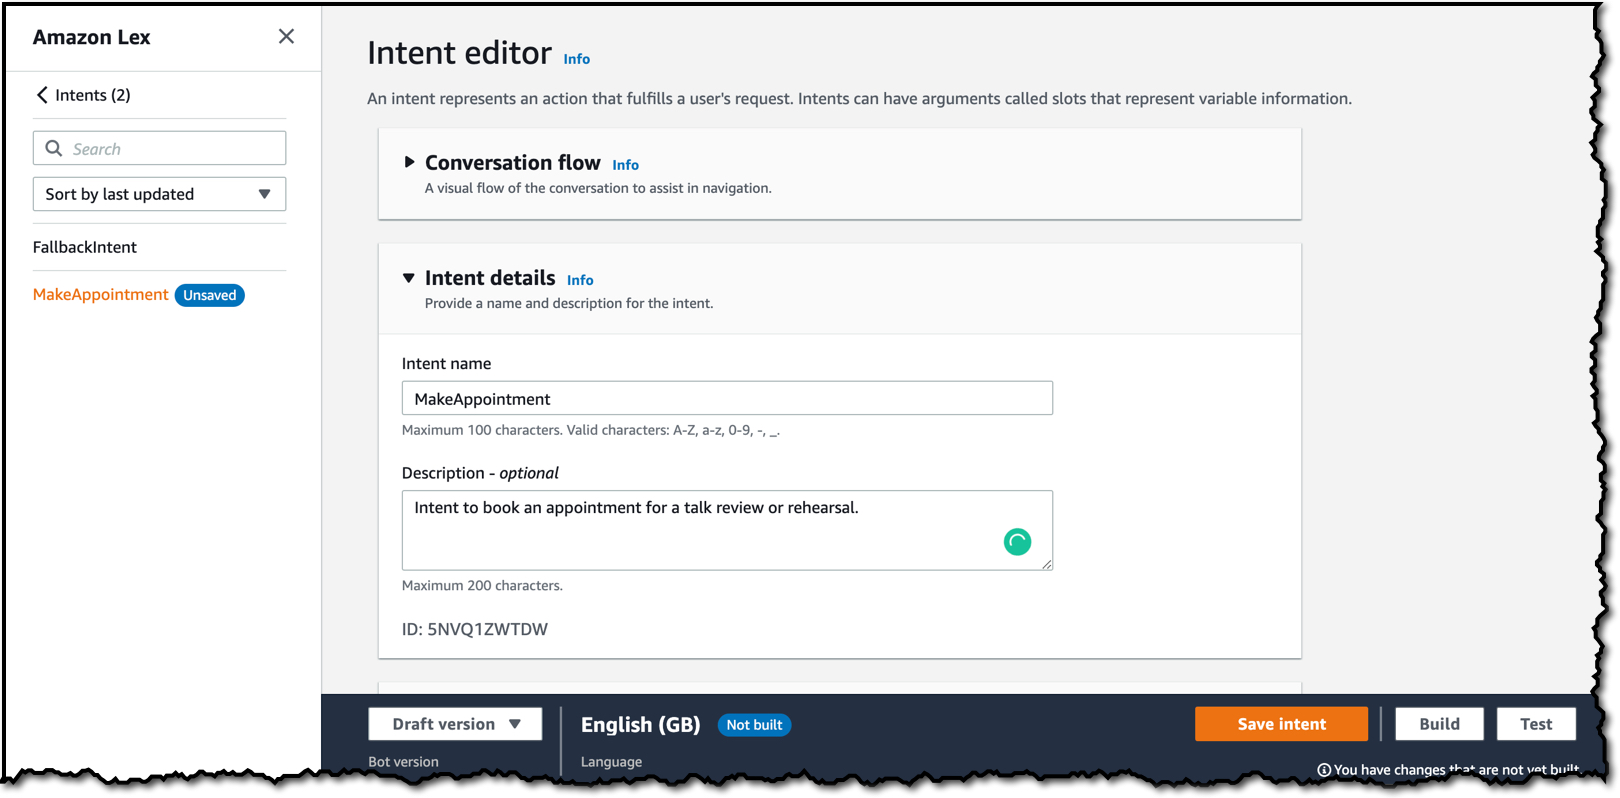
I can now start defining intents for my bot, and I can begin the iterative process of building and testing my bot. I won’t go into all of the details of how to create a bot or show you all of the intents I added, as we have better tutorials that can show you that step-by-step, but I will point out a few new features that make this new enhanced console really compelling.

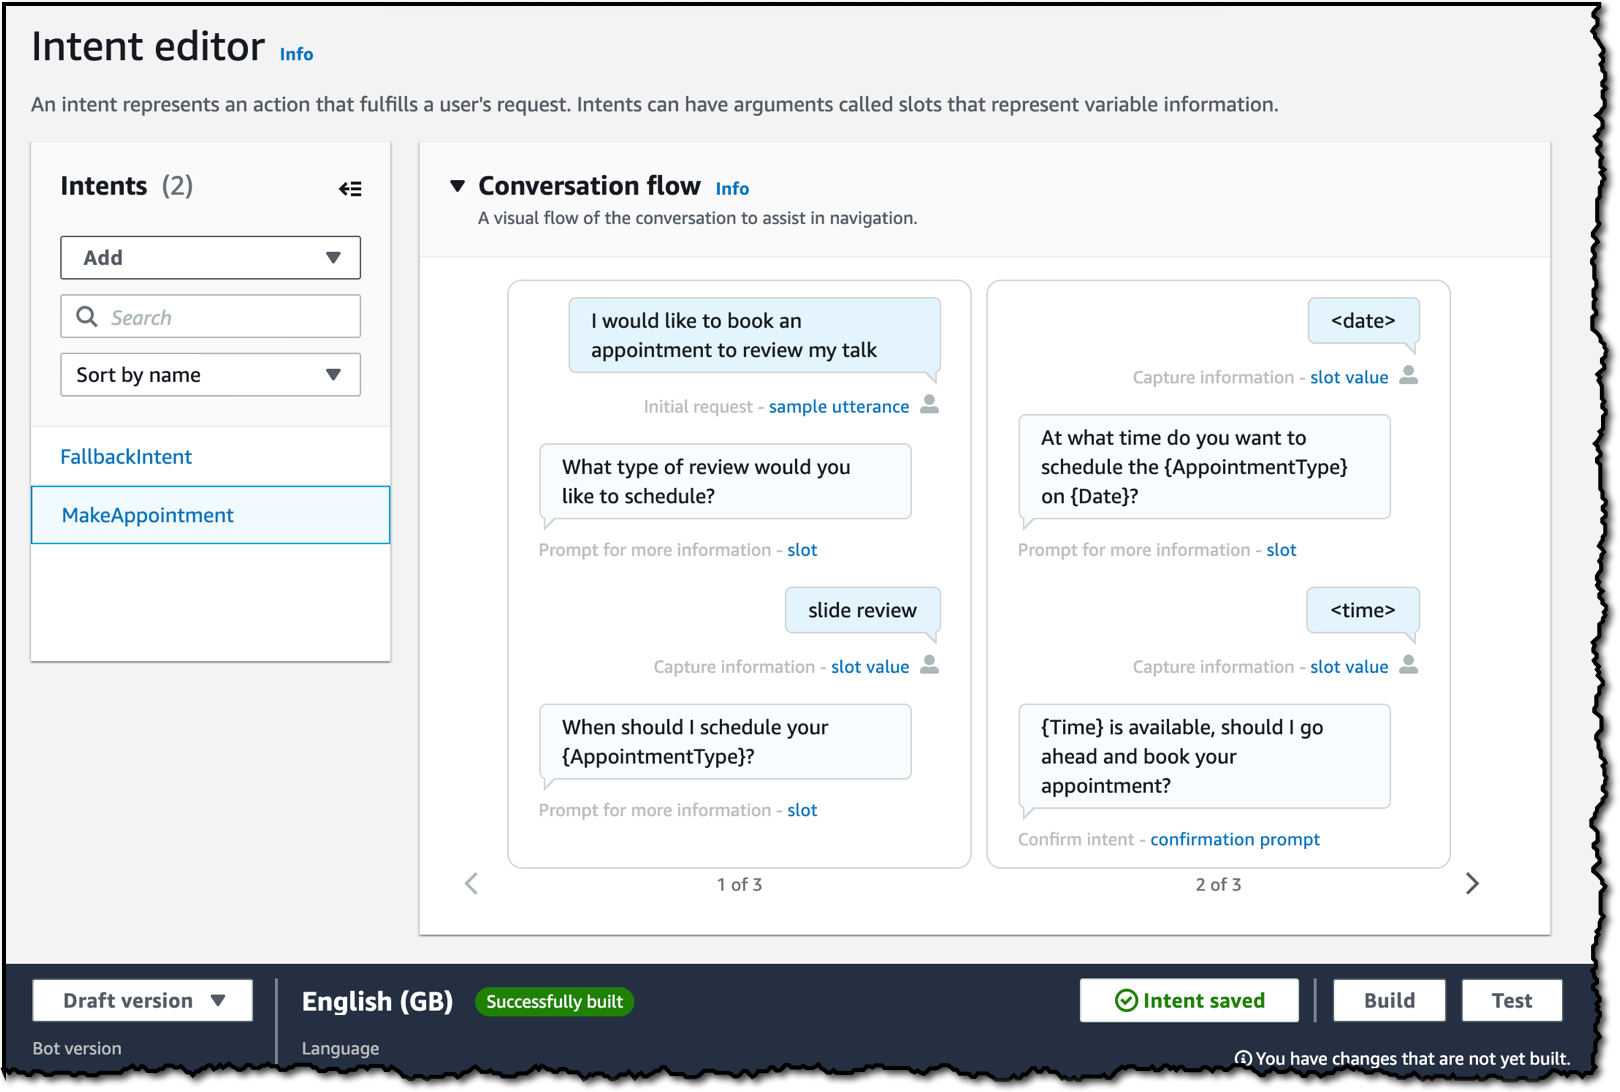
The new Conversation flow provides you with a visual flow of the conversation, and you can see how the sample utterances you provide and how your conversation might work in the real world. I love this feature because you can click on the various elements, and it will take you to where you can make changes. For example, I can click on the prompt What type of review would you like to schedule and I am taken to the place where I can edit this prompt.

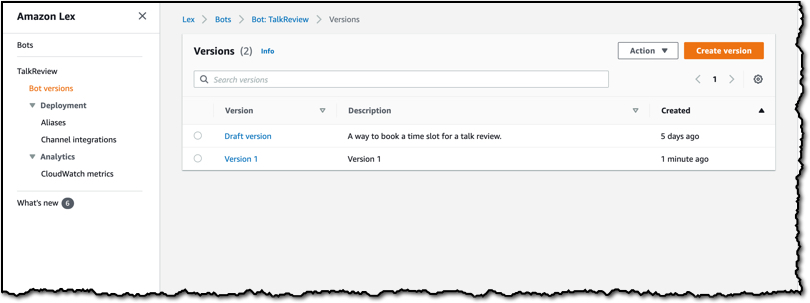
The new console has a very well thought-out approach to versioning a bot. At anytime, on the Bot versions screen, I can click Create version, and it will take a snapshot of the state of the bot’s current configuration. I can then associate that with an alias. For example, in my application, I have an alias called Production. This Production alias is associated with Version 1. Still, at any time, I could switch it to use a different version or even roll back to a previous version if I discover problems.

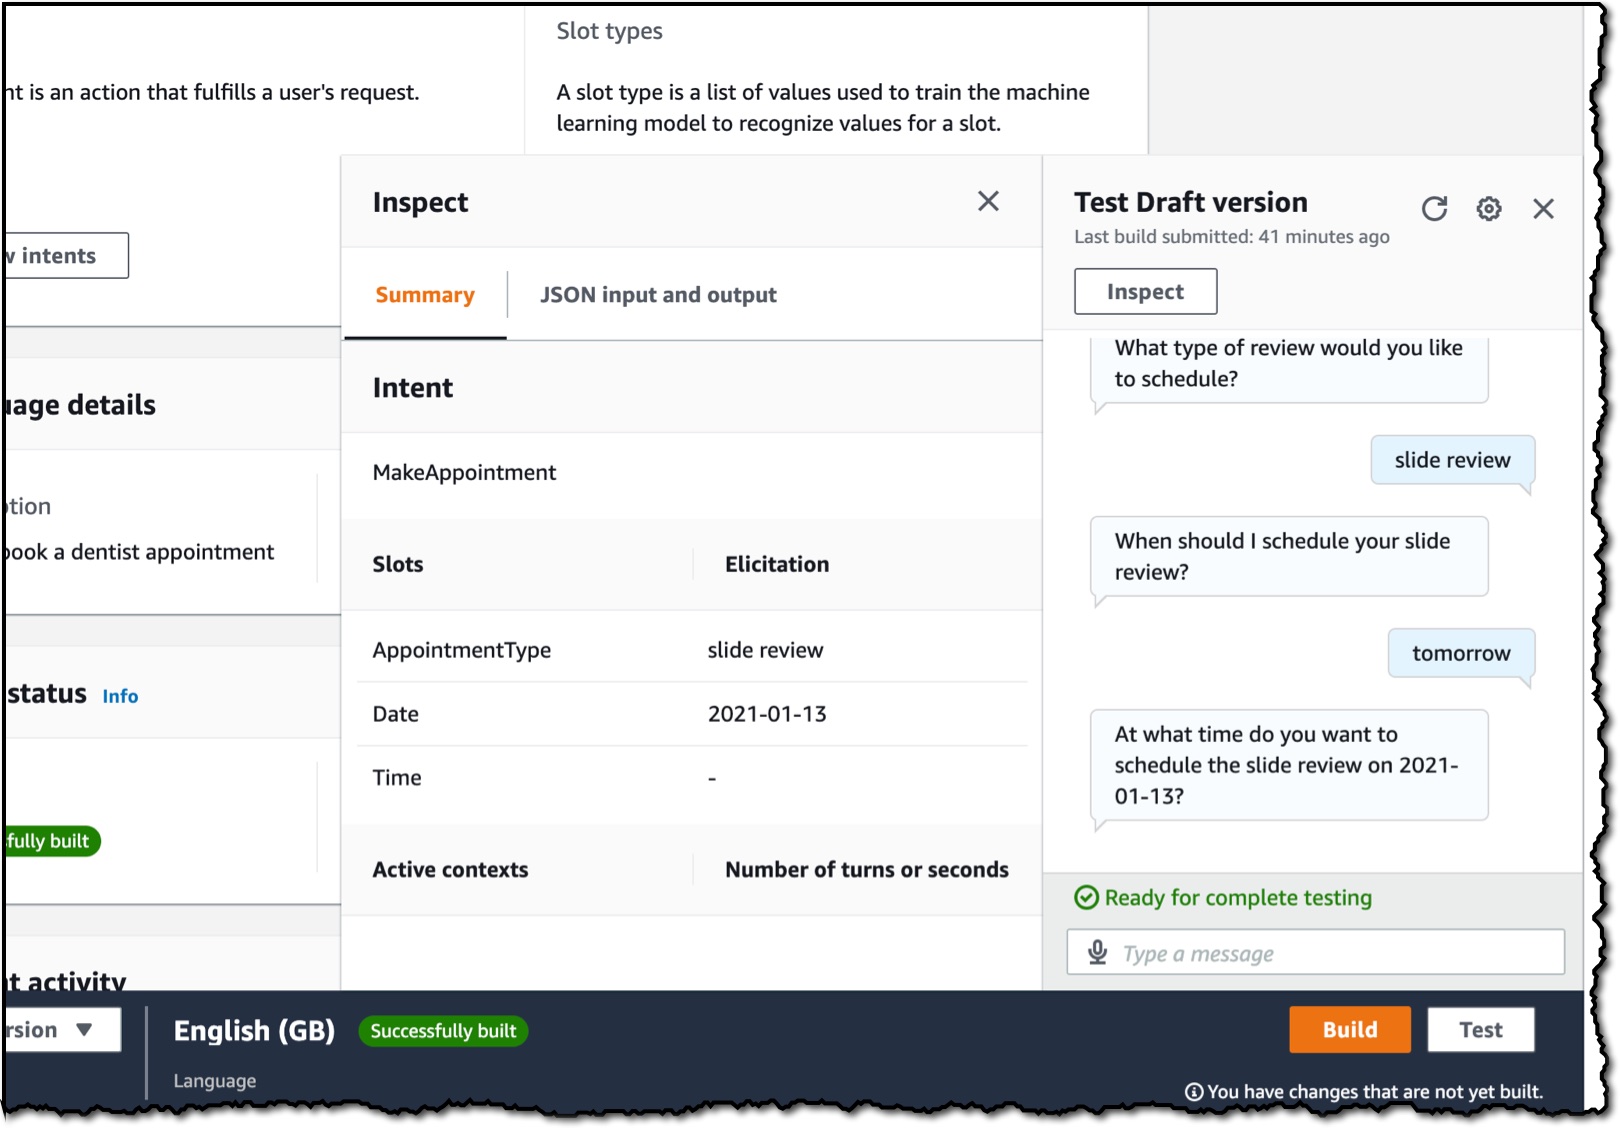
The testing experience is now very streamlined. Once I have built the bot, I can click the test button on the bottom right hand of the screen and start speaking to the bot and testing the experience. You can also expand the Inspect window, which gives you details about the conversations state, and you can also explore the raw JSON inputs and outputs.

Things to know
Here are a couple of important things to keep in mind when you use the enhanced console

  • Integration with Amazon Connect – Currently, bots built in the new console cannot be integrated with Amazon Connect contact flows. We plan to provide this integration as part of the near-term roadmap. You can use the current console and existing APIs to create and integrate bots with Amazon Connect.
  • Pricing – You only pay for what you use. The charges remain the same for existing audio and text APIs, renamed as RecognizeUtterance and RecognizeText. For the new Streaming capabilities, please refer to the pricing detail here.
  • All existing APIs and bots will continue to be supported. The newly announced features are only available in the new console and V2 APIs.

Go Build
Lex enhanced console is available now, and you can start using it today. The enhanced experience and V2 APIs are available in all existing regions and support all current languages. So, please give this console a try and let us know what you think. To learn more, check out the documentation for the console and the streaming API.

Happy Building!
— Martin

re:Invent – New security sessions launching soon

Post Syndicated from Marta Taggart original https://aws.amazon.com/blogs/security/reinvent-new-security-sessions-launching-soon/

Where did the last month go? Were you able to catch all of the sessions in the Security, Identity, and Compliance track you hoped to see at AWS re:Invent? If you missed any, don’t worry—you can stream all the sessions released in 2020 via the AWS re:Invent website. Additionally, we’re starting 2021 with all new sessions that you can stream live January 12–15. Here are the new Security, Identity, and Compliance sessions—each session is offered at multiple times, so you can find the time that works best for your location and schedule.

Protecting sensitive data with Amazon Macie and Amazon GuardDuty – SEC210
Himanshu Verma, AWS Speaker

Tuesday, January 12 – 11:00 AM to 11:30 AM PST
Tuesday, January 12 – 7:00 PM to 7:30 PM PST
Wednesday, January 13 – 3:00 AM to 3:30 AM PST

As organizations manage growing volumes of data, identifying and protecting your sensitive data can become increasingly complex, expensive, and time-consuming. In this session, learn how Amazon Macie and Amazon GuardDuty together provide protection for your data stored in Amazon S3. Amazon Macie automates the discovery of sensitive data at scale and lowers the cost of protecting your data. Amazon GuardDuty continuously monitors and profiles S3 data access events and configurations to detect suspicious activities. Come learn about these security services and how to best use them for protecting data in your environment.

BBC: Driving security best practices in a decentralized organization – SEC211
Apurv Awasthi, AWS Speaker
Andrew Carlson, Sr. Software Engineer – BBC

Tuesday, January 12 – 1:15 PM to 1:45 PM PST
Tuesday, January 12 – 9:15 PM to 9:45 PM PST
Wednesday, January 13 – 5:15 AM to 5:45 AM PST

In this session, Andrew Carlson, engineer at BBC, talks about BBC’s journey while adopting AWS Secrets Manager for lifecycle management of its arbitrary credentials such as database passwords, API keys, and third-party keys. He provides insight on BBC’s secrets management best practices and how the company drives these at enterprise scale in a decentralized environment that has a highly visible scope of impact.

Get ahead of the curve with DDoS Response Team escalations – SEC321
Fola Bolodeoku, AWS Speaker

Tuesday, January 12 – 3:30 PM to 4:00 PM PST
Tuesday, January 12 – 11:30 PM to 12:00 AM PST
Wednesday, January – 7:30 AM to 8:00 AM PST

This session identifies tools and tricks that you can use to prepare for application security escalations, with lessons learned provided by the AWS DDoS Response Team. You learn how AWS customers have used different AWS offerings to protect their applications, including network access control lists, security groups, and AWS WAF. You also learn how to avoid common misconfigurations and mishaps observed by the DDoS Response Team, and you discover simple yet effective actions that you can take to better protect your applications’ availability and security controls.

Network security for serverless workloads – SEC322
Alex Tomic, AWS Speaker

Thursday, January 14 -1:30 PM to 2:00 PM PST
Thursday, January 14 – 9:30 PM to 10:00 PM PST
Friday, January 15 – 5:30 AM to 6:00 AM PST

Are you building a serverless application using services like Amazon API Gateway, AWS Lambda, Amazon DynamoDB, Amazon Aurora, and Amazon SQS? Would you like to apply enterprise network security to these AWS services? This session covers how network security concepts like encryption, firewalls, and traffic monitoring can be applied to a well-architected AWS serverless architecture.

Building your cloud incident response program – SEC323
Freddy Kasprzykowski, AWS Speaker

Wednesday, January 13 – 9:00 AM to 9:30 AM PST
Wednesday, January 13 – 5:00 PM to 5:30 PM PST
Thursday, January 14 – 1:00 AM to 1:30 AM PST

You’ve configured your detection services and now you’ve received your first alert. This session provides patterns that help you understand what capabilities you need to build and run an effective incident response program in the cloud. It includes a review of some logs to see what they tell you and a discussion of tools to analyze those logs. You learn how to make sure that your team has the right access, how automation can help, and which incident response frameworks can guide you.

Beyond authentication: Guide to secure Amazon Cognito applications – SEC324
Mahmoud Matouk, AWS Speaker

Wednesday, January 13 – 2:15 PM to 2:45 PM PST
Wednesday, January 13 – 10:15 PM to 10:45 PM PST
Thursday, January 14 – 6:15 AM to 6:45 AM PST

Amazon Cognito is a flexible user directory that can meet the needs of a number of customer identity management use cases. Web and mobile applications can integrate with Amazon Cognito in minutes to offer user authentication and get standard tokens to be used in token-based authorization scenarios. This session covers best practices that you can implement in your application to secure and protect tokens. You also learn about new Amazon Cognito features that give you more options to improve the security and availability of your application.

Event-driven data security using Amazon Macie – SEC325
Neha Joshi, AWS Speaker

Thursday, January 14 – 8:00 AM to 8:30 AM PST
Thursday, January 14 – 4:00 PM to 4:30 PM PST
Friday, January 15 – 12:00 AM to 12:30 AM PST

Amazon Macie sensitive data discovery jobs for Amazon S3 buckets help you discover sensitive data such as personally identifiable information (PII), financial information, account credentials, and workload-specific sensitive information. In this session, you learn about an automated approach to discover sensitive information whenever changes are made to the objects in your S3 buckets.

Instance containment techniques for effective incident response – SEC327
Jonathon Poling, AWS Speaker

Thursday, January 14 – 10:15 AM to 10:45 AM PST
Thursday, January 14 – 6:15 PM to 6:45 PM PST
Friday, January 15 – 2:15 AM to 2:45 AM PST

In this session, learn about several instance containment and isolation techniques, ranging from simple and effective to more complex and powerful, that leverage native AWS networking services and account configuration techniques. If an incident happens, you may have questions like “How do we isolate the system while preserving all the valuable artifacts?” and “What options do we even have?”. These are valid questions, but there are more important ones to discuss amidst a (possible) incident. Join this session to learn highly effective instance containment techniques in a crawl-walk-run approach that also facilitates preservation and collection of valuable artifacts and intelligence.

Trusted connects for government workloads – SEC402
Brad Dispensa, AWS Speaker

Wednesday, January 13 – 11:15 AM to 11:45 AM PST
Wednesday, January 13 – 7:15 PM to 7:45 PM PST
Thursday, January 14 – 3:15 AM to 3:45 AM PST

Cloud adoption across the public sector is making it easier to provide government workforces with seamless access to applications and data. With this move to the cloud, we also need updated security guidance to ensure public-sector data remain secure. For example, the TIC (Trusted Internet Connections) initiative has been a requirement for US federal agencies for some time. The recent TIC-3 moves from prescriptive guidance to an outcomes-based model. This session walks you through how to leverage AWS features to better protect public-sector data using TIC-3 and the National Institute of Standards and Technology (NIST) Cybersecurity Framework (CSF). Also, learn how this might map into other geographies.

I look forward to seeing you in these sessions. Please see the re:Invent agenda for more details and to build your schedule.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Marta Taggart

Marta is a Seattle-native and Senior Program Manager in AWS Security, where she focuses on privacy, content development, and educational programs. Her interest in education stems from two years she spent in the education sector while serving in the Peace Corps in Romania. In her free time, she’s on a global hunt for the perfect cup of coffee.

Optimizing AWS Lambda cost and performance using AWS Compute Optimizer

Post Syndicated from Chad Schmutzer original https://aws.amazon.com/blogs/compute/optimizing-aws-lambda-cost-and-performance-using-aws-compute-optimizer/

This post is authored by Brooke Chen, Senior Product Manager for AWS Compute Optimizer, Letian Feng, Principal Product Manager for AWS Compute Optimizer, and Chad Schmutzer, Principal Developer Advocate for Amazon EC2

Optimizing compute resources is a critical component of any application architecture. Over-provisioning compute can lead to unnecessary infrastructure costs, while under-provisioning compute can lead to poor application performance.

Launched in December 2019, AWS Compute Optimizer is a recommendation service for optimizing the cost and performance of AWS compute resources. It generates actionable optimization recommendations tailored to your specific workloads. Over the last year, thousands of AWS customers reduced compute costs up to 25% by using Compute Optimizer to help choose the optimal Amazon EC2 instance types for their workloads.

One of the most frequent requests from customers is for AWS Lambda recommendations in Compute Optimizer. Today, we announce that Compute Optimizer now supports memory size recommendations for Lambda functions. This allows you to reduce costs and increase performance for your Lambda-based serverless workloads. To get started, opt in for Compute Optimizer to start finding recommendations.

Overview

With Lambda, there are no servers to manage, it scales automatically, and you only pay for what you use. However, choosing the right memory size settings for a Lambda function is still an important task. Computer Optimizer uses machine-learning based memory recommendations to help with this task.

These recommendations are available through the Compute Optimizer console, AWS CLI, AWS SDK, and the Lambda console. Compute Optimizer continuously monitors Lambda functions, using historical performance metrics to improve recommendations over time. In this blog post, we walk through an example to show how to use this feature.

Using Compute Optimizer for Lambda

This tutorial uses the AWS CLI v2 and the AWS Management Console.

In this tutorial, we setup two compute jobs that run every minute in AWS Region US East (N. Virginia). One job is more CPU intensive than the other. Initial tests show that the invocation times for both jobs typically last for less than 60 seconds. The goal is to either reduce cost without much increase in duration, or reduce the duration in a cost-efficient manner.

Based on these requirements, a serverless solution can help with this task. Amazon EventBridge can schedule the Lambda functions using rules. To ensure that the functions are optimized for cost and performance, you can use the memory recommendation support in Compute Optimizer.

In your AWS account, opt in to Compute Optimizer to start analyzing AWS resources. Ensure you have the appropriate IAM permissions configured – follow these steps for guidance. If you prefer to use the console to opt in, follow these steps. To opt in, enter the following command in a terminal window:

$ aws compute-optimizer update-enrollment-status --status Active

Once you enable Compute Optimizer, it starts to scan for functions that have been invoked for at least 50 times over the trailing 14 days. The next section shows two example scheduled Lambda functions for analysis.

Example Lambda functions

The code for the non-CPU intensive job is below. A Lambda function named lambda-recommendation-test-sleep is created with memory size configured as 1024 MB. An EventBridge rule is created to trigger the function on a recurring 1-minute schedule:

import json
import time

def lambda_handler(event, context):
  time.sleep(30)
  x=[0]*100000000
  return {
    'statusCode': 200,
    'body': json.dumps('Hello World!')
  }

The code for the CPU intensive job is below. A Lambda function named lambda-recommendation-test-busy is created with memory size configured as 128 MB. An EventBridge rule is created to trigger the function on a recurring 1-minute schedule:

import json
import random

def lambda_handler(event, context):
  random.seed(1)
  x=0
  for i in range(0, 20000000):
    x+=random.random()

  return {
    'statusCode': 200,
    'body': json.dumps('Sum:' + str(x))
  }

Understanding the Compute Optimizer recommendations

Compute Optimizer needs a history of at least 50 invocations of a Lambda function over the trailing 14 days to deliver recommendations. Recommendations are created by analyzing function metadata such as memory size, timeout, and runtime, in addition to CloudWatch metrics such as number of invocations, duration, error count, and success rate.

Compute Optimizer will gather the necessary information to provide memory recommendations for Lambda functions, and make them available within 48 hours. Afterwards, these recommendations will be refreshed daily.

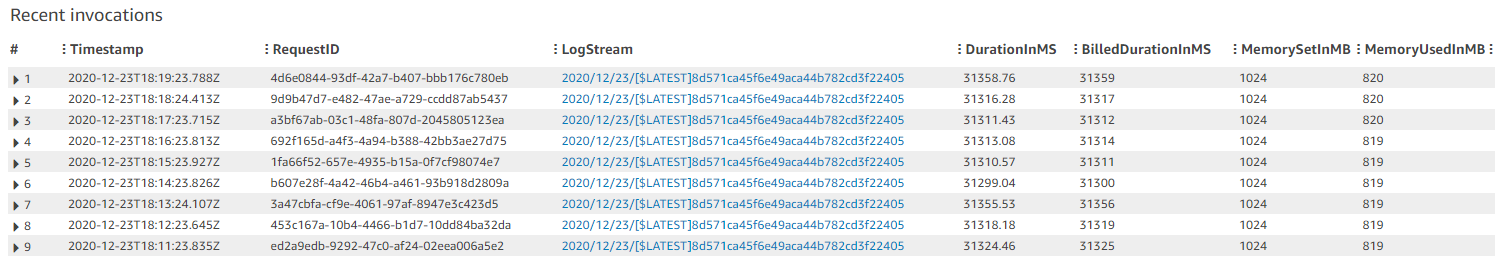
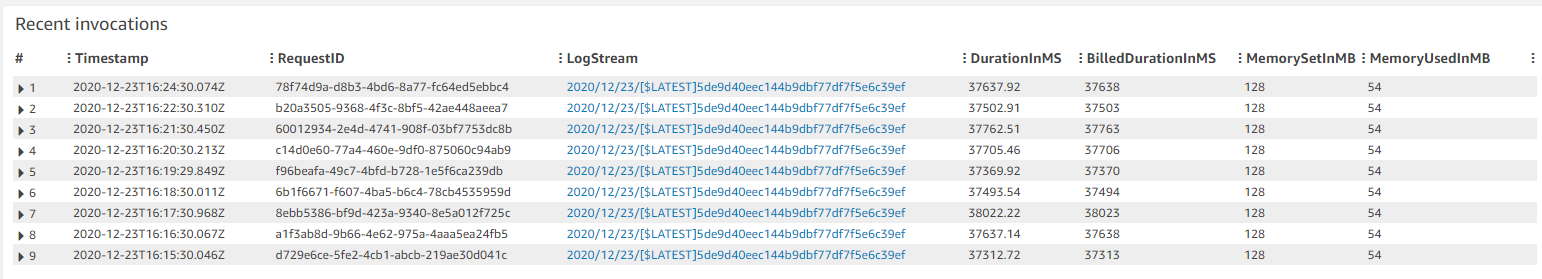
These are recent invocations for the non-CPU intensive function:

Recent invocations for the non-CPU intensive function

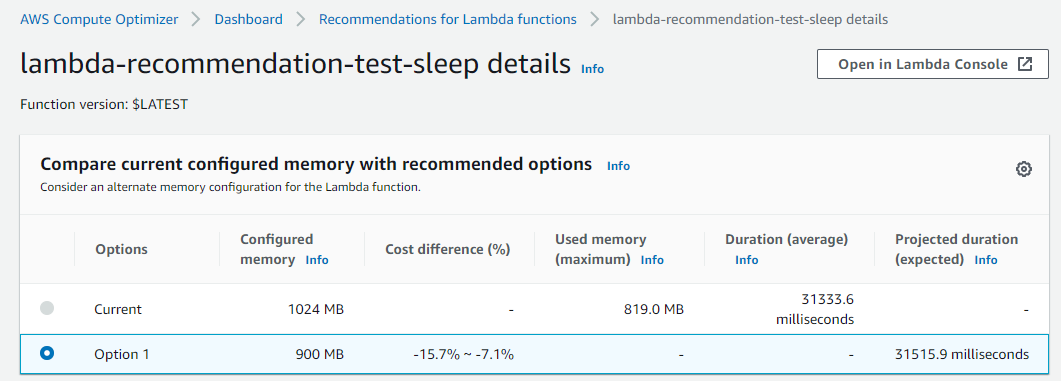
Function duration is approximately 31.3 seconds with a memory setting of 1024 MB, resulting in a duration cost of about $0.00052 per invocation. Here are the recommendations for this function in the Compute Optimizer console:

Recommendations for this function in the Compute Optimizer console

The function is Not optimized with a reason of Memory over-provisioned. You can also fetch the same recommendation information via the CLI:

$ aws compute-optimizer \
  get-lambda-function-recommendations \
  --function-arns arn:aws:lambda:us-east-1:123456789012:function:lambda-recommendation-test-sleep
{
    "lambdaFunctionRecommendations": [
        {
            "utilizationMetrics": [
                {
                    "name": "Duration",
                    "value": 31333.63587049883,
                    "statistic": "Average"
                },
                {
                    "name": "Duration",
                    "value": 32522.04,
                    "statistic": "Maximum"
                },
                {
                    "name": "Memory",
                    "value": 817.67049838188,
                    "statistic": "Average"
                },
                {
                    "name": "Memory",
                    "value": 819.0,
                    "statistic": "Maximum"
                }
            ],
            "currentMemorySize": 1024,
            "lastRefreshTimestamp": 1608735952.385,
            "numberOfInvocations": 3090,
            "functionArn": "arn:aws:lambda:us-east-1:123456789012:function:lambda-recommendation-test-sleep:$LATEST",
            "memorySizeRecommendationOptions": [
                {
                    "projectedUtilizationMetrics": [
                        {
                            "name": "Duration",
                            "value": 30015.113193697029,
                            "statistic": "LowerBound"
                        },
                        {
                            "name": "Duration",
                            "value": 31515.86878891883,
                            "statistic": "Expected"
                        },
                        {
                            "name": "Duration",
                            "value": 33091.662123300975,
                            "statistic": "UpperBound"
                        }
                    ],
                    "memorySize": 900,
                    "rank": 1
                }
            ],
            "functionVersion": "$LATEST",
            "finding": "NotOptimized",
            "findingReasonCodes": [
                "MemoryOverprovisioned"
            ],
            "lookbackPeriodInDays": 14.0,
            "accountId": "123456789012"
        }
    ]
}

The Compute Optimizer recommendation contains useful information about the function. Most importantly, it has determined that the function is over-provisioned for memory. The attribute findingReasonCodes shows the value MemoryOverprovisioned. In memorySizeRecommendationOptions, Compute Optimizer has found that using a memory size of 900 MB results in an expected invocation duration of approximately 31.5 seconds.

For non-CPU intensive jobs, reducing the memory setting of the function often doesn’t have a negative impact on function duration. The recommendation confirms that you can reduce the memory size from 1024 MB to 900 MB, saving cost without significantly impacting duration. The new duration cost per invocation saves approximately 12%.

The Compute Optimizer console validates these calculations:

Compute Optimizer console validates these calculations

These are recent invocations for the second function which is CPU-intensive:

Recent invocations for the second function which is CPU-intensive

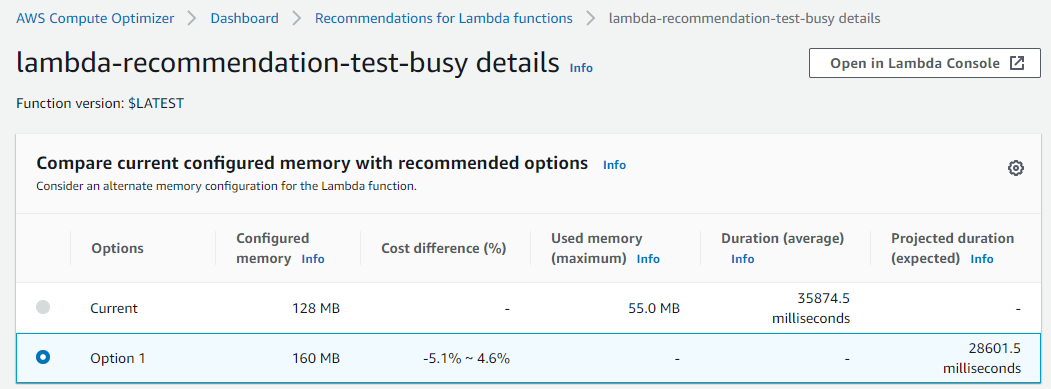
The function duration is about 37.5 seconds with a memory setting of 128 MB, resulting in a duration cost of about $0.000078 per invocation. The recommendations for this function appear in the Compute Optimizer console:

recommendations for this function appear in the Compute Optimizer console

The function is also Not optimized with a reason of Memory under-provisioned. The same recommendation information is available via the CLI:

$ aws compute-optimizer \
  get-lambda-function-recommendations \
  --function-arns arn:aws:lambda:us-east-1:123456789012:function:lambda-recommendation-test-busy
{
    "lambdaFunctionRecommendations": [
        {
            "utilizationMetrics": [
                {
                    "name": "Duration",
                    "value": 36006.85851551957,
                    "statistic": "Average"
                },
                {
                    "name": "Duration",
                    "value": 38540.43,
                    "statistic": "Maximum"
                },
                {
                    "name": "Memory",
                    "value": 53.75978407557355,
                    "statistic": "Average"
                },
                {
                    "name": "Memory",
                    "value": 55.0,
                    "statistic": "Maximum"
                }
            ],
            "currentMemorySize": 128,
            "lastRefreshTimestamp": 1608725151.752,
            "numberOfInvocations": 741,
            "functionArn": "arn:aws:lambda:us-east-1:123456789012:function:lambda-recommendation-test-busy:$LATEST",
            "memorySizeRecommendationOptions": [
                {
                    "projectedUtilizationMetrics": [
                        {
                            "name": "Duration",
                            "value": 27340.37604781184,
                            "statistic": "LowerBound"
                        },
                        {
                            "name": "Duration",
                            "value": 28707.394850202432,
                            "statistic": "Expected"
                        },
                        {
                            "name": "Duration",
                            "value": 30142.764592712556,
                            "statistic": "UpperBound"
                        }
                    ],
                    "memorySize": 160,
                    "rank": 1
                }
            ],
            "functionVersion": "$LATEST",
            "finding": "NotOptimized",
            "findingReasonCodes": [
                "MemoryUnderprovisioned"
            ],
            "lookbackPeriodInDays": 14.0,
            "accountId": "123456789012"
        }
    ]
}

For this function, Compute Optimizer has determined that the function’s memory is under-provisioned. The value of findingReasonCodes is MemoryUnderprovisioned. The recommendation is to increase the memory from 128 MB to 160 MB.

This recommendation may seem counter-intuitive, since the function only uses 55 MB of memory per invocation. However, Lambda allocates CPU and other resources linearly in proportion to the amount of memory configured. This means that increasing the memory allocation to 160 MB also reduces the expected duration to around 28.7 seconds. This is because a CPU-intensive task also benefits from the increased CPU performance that comes with the additional memory.

After applying this recommendation, the new expected duration cost per invocation is approximately $0.000075. This means that for almost no change in duration cost, the job latency is reduced from 37.5 seconds to 28.7 seconds.

The Compute Optimizer console validates these calculations:

Compute Optimizer console validates these calculations

Applying the Compute Optimizer recommendations

To optimize the Lambda functions using Compute Optimizer recommendations, use the following CLI command:

$ aws lambda update-function-configuration \
  --function-name lambda-recommendation-test-sleep \
  --memory-size 900

After invoking the function multiple times, we can see metrics of these invocations in the console. This shows that the function duration has not changed significantly after reducing the memory size from 1024 MB to 900 MB. The Lambda function has been successfully cost-optimized without increasing job duration:

Console shows the metrics from recent invocations

To apply the recommendation to the CPU-intensive function, use the following CLI command:

$ aws lambda update-function-configuration \
  --function-name lambda-recommendation-test-busy \
  --memory-size 160

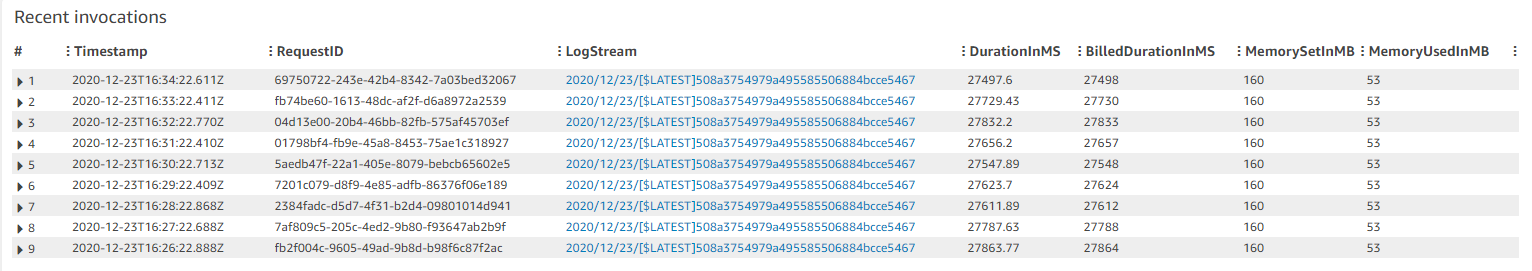
After invoking the function multiple times, the console shows that the invocation duration is reduced to about 28 seconds. This matches the recommendation’s expected duration. This shows that the function is now performance-optimized without a significant cost increase:

Console shows that the invocation duration is reduced to about 28 seconds

Final notes

A couple of final notes:

  • Not every function will receive a recommendation. Compute optimizer only delivers recommendations when it has high confidence that these recommendations may help reduce cost or reduce execution duration.
  • As with any changes you make to an environment, we strongly advise that you test recommended memory size configurations before applying them into production.

Conclusion

You can now use Compute Optimizer for serverless workloads using Lambda functions. This can help identify the optimal Lambda function configuration options for your workloads. Compute Optimizer supports memory size recommendations for Lambda functions in all AWS Regions where Compute Optimizer is available. These recommendations are available to you at no additional cost. You can get started with Compute Optimizer from the console.

To learn more visit Getting started with AWS Compute Optimizer.


2020 ISO certificates are here, with a new Region and increased in-scope services

Post Syndicated from Anastasia Strebkova original https://aws.amazon.com/blogs/security/2020-iso-certificates-are-here-with-a-new-region-and-increased-in-scope-services/

Amazon Web Services (AWS) successfully completed the surveillance audits with no findings for ISO 9001, 27001, 27017, or 27018. Ernst and Young Certify Point auditors reissued the certificates on November 6, 2020. The certificates validate ISO compliance of our Information Security Management System from the perspective of third-party auditors.

We included 9 additional AWS services in scope for these audits in 2020, validated against ISO 9001, 27001, 27017, and 27018. We also added a new Cape Town Region to the scope, which was validated against ISO 9001, 27001, 27017, and 27018 standards before the general launch.

The services added to our ISO program during the 2020 audit cycle include the following:

AWS CloudEndure now expands to include ISO 9001, 27017, and 27018, in addition to the existing 27001 certification.

The list of ISO certified services is available on the AWS webpage, and we provide the certifications online and in the console via AWS Artifact, as well.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Anastasia Strebkova

Anastasia is a Security Assurance Manager at Amazon Web Services on the Global Audits team, managing the AWS ISO portfolio. She has previously worked on IT audits, governance, risk, privacy, business continuity, and information security program management for cloud enterprises. Anastasia holds a Bachelor of Arts degree in Civil Law from Moscow Law Academy.

138 AWS services achieve CSA STAR Level 2 certification

Post Syndicated from Anastasia Strebkova original https://aws.amazon.com/blogs/security/138-aws-services-achieve-csa-star-level-2-certification/

We’re excited to announce that Amazon Web Services (AWS) has achieved Cloud Security Alliance (CSA) Security Trust Assurance and Risk (STAR) Level 2 certification with no findings.

CSA STAR Level 2 certification is a rigorous third-party independent assessment of the security of a cloud service provider. The certification demonstrates that a cloud service provider conforms to the applicable requirements of the ISO/IEC 27001:2013 management system standard and has addressed requirements critical to cloud security as outlined in the CSA Cloud Controls Matrix criteria. CSA STAR Level 2 certification verifies for cloud customers the use of best practices and the security posture of AWS Cloud offerings.

Ernst and Young Certify Point issued the certificate on November 6, 2020. The covered AWS Regions are included on the CSA STAR Level 2 certificate and the full list of AWS services in scope for CSA STAR Level 2 is available on our ISO and CSA STAR Certified webpage. You can view and download our CSA STAR Level 2 certificate online and in the console via AWS Artifact. The certificate is also available for download from the CSA STAR certification registry.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Anastasia Strebkova

Anastasia is a Security Assurance Manager at Amazon Web Services on the Global Audits team, managing the AWS ISO portfolio. She has previously worked on IT audits, governance, risk, privacy, business continuity, and information security program management for cloud enterprises. Anastasia holds a Bachelor of Arts degree in Civil Law from Moscow Law Academy.

AWS extends its TISAX scope to cover the London and Paris Regions

Post Syndicated from Clara Lim original https://aws.amazon.com/blogs/security/aws-extends-tisax-scope-to-cover-london-paris-regions/

We’re excited to announce the completion of Trusted Information Security Assessment Exchange (TISAX) certification on December 08, 2020 for the London and Paris regions. These regions were assessed at the HIGH protection level (AL 2) for the control domains Information Handling and Data Protection, according to article 28 (“Processor”) of the European General Data Protection Regulation (GDPR).

The TISAX certification helps provide automotive industry organizations with the assurance they need to build secure applications and services in the cloud. The certification was established by the German Association of the Automotive Industry (VDA) and is governed by the European Network Exchange (ENX).

With this scope expansion, a total of 10 regions globally (Seattle, Frankfurt, Ireland, Oregon, Ohio, Northern Virginia, Canada, Seoul, London, and Paris) are currently certified for TISAX and demonstrate a consistent and standardized approach to information security systems for the automotive industry.

An independent third-party auditor conducted and accredited the assessment. Automotive customers can rely on the AWS TISAX assessment results and labels published on the ENX Portal for timely exchange of compliance status with their supply chains. The scope ID and assessment ID are STRN58 and AYZ39G, respectively.

For more information, see Trusted Information Security Assessment Exchange.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Clara Lim

Clara is the Audit Program Manager for the Asia Pacific Region, leading multiple security certification programs. Clara is passionate about leveraging her decade-long experience to deliver compliance programs that provide assurance and build trust with customers.

Using self-hosted Apache Kafka as an event source for AWS Lambda

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/using-self-hosted-apache-kafka-as-an-event-source-for-aws-lambda/

Apache Kafka is an open source event streaming platform used to support workloads such as data pipelines and streaming analytics. Apache Kafka is a distributed streaming platform that it is conceptually similar to Amazon Kinesis.

With the launch of Kafka as an event source for Lambda, you can now consume messages from a topic in a Lambda function. This makes it easier to integrate your self-hosted Kafka clusters with downstream serverless workflows.

In this blog post, I explain how to set up an Apache Kafka cluster on Amazon EC2 and configure key elements in the networking configuration. I also show how to create a Lambda function to consume messages from a Kafka topic. Although the process is similar to using Amazon Managed Streaming for Apache Kafka (Amazon MSK) as an event source, there are also some important differences.

Overview

Using Kafka as an event source operates in a similar way to using Amazon SQS or Amazon Kinesis. In all cases, the Lambda service internally polls for new records or messages from the event source, and then synchronously invokes the target Lambda function. Lambda reads the messages in batches and provides the message batches to your function in the event payload.

Lambda is a consumer application for your Kafka topic. It processes records from one or more partitions and sends the payload to the target function. Lambda continues to process batches until there are no more messages in the topic.

Configuring networking for self-hosted Kafka

It’s best practice to deploy the Amazon EC2 instances running Kafka in private subnets. For the Lambda function to poll the Kafka instances, you must ensure that there is a NAT Gateway running in the public subnet of each Region.

It’s possible to route the traffic to a single NAT Gateway in one AZ for test and development workloads. For redundancy in production workloads, it’s recommended that there is one NAT Gateway available in each Availability Zone. This walkthrough creates the following architecture:

Self-hosted Kafka architecture

  1. Deploy a VPC with public and private subnets and a NAT Gateway that enables internet access. To configure this infrastructure with AWS CloudFormation, deploy this template.
  2. From the VPC console, edit the default security group created by this template to provide inbound access to the following ports:
    • Custom TCP: ports 2888–3888 from all sources.
    • SSH (port 22), restricted to your own IP address.
    • Custom TCP: port 2181 from all sources.
    • Custom TCP: port 9092 from all sources.
    • All traffic from the same security group identifier.

Security Group configuration

Deploying the EC2 instances and installing Kafka

Next, you deploy the EC2 instances using this network configuration and install the Kafka application:

  1. From the EC2 console, deploy an instance running Ubuntu Server 18.04 LTS. Ensure that there is one instance in each private subnet, in different Availability Zones. Assign the default security group configured by the template.
  2. Next, deploy another EC2 instance in either of the public subnets. This is a bastion host used to access the private instances. Assign the default security group configured by the template.EC2 instances
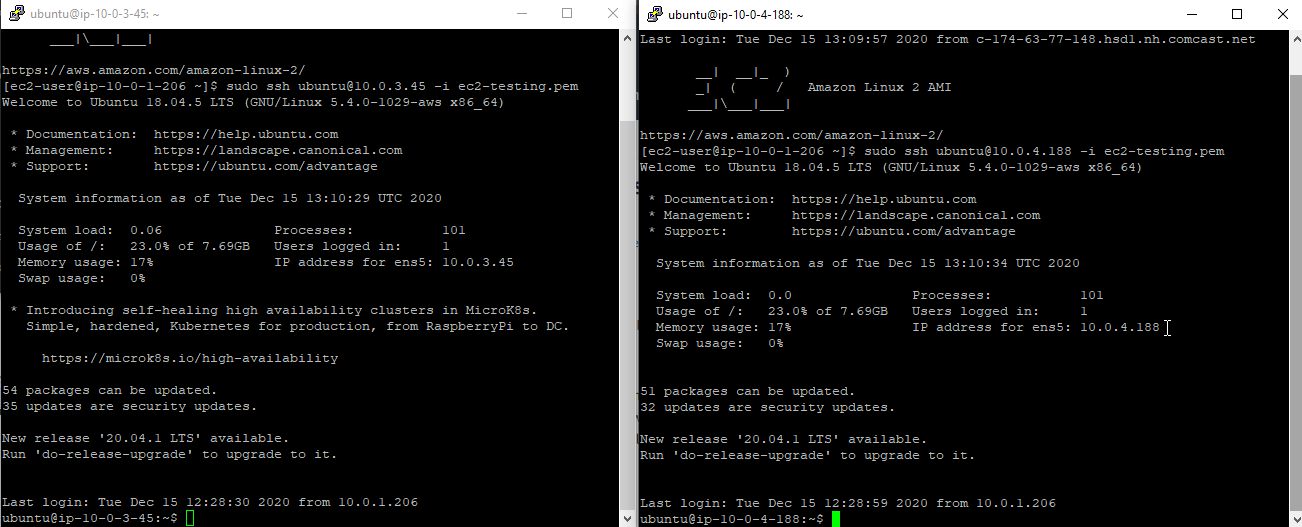
  3. Connect to the bastion host, then SSH to the first private EC2 instance using the method for your preferred operating system. This post explains different methods. Repeat the process in another terminal for the second private instance.EC2 terminals
  4. On each instance, install Java:
    sudo add-apt-repository ppa:webupd8team/java
    sudo apt update
    sudo apt install openjdk-8-jdk
    java –version
  5. On each instance, install Kafka:
    wget http://www-us.apache.org/dist/kafka/2.3.1/kafka_2.12-2.3.1.tgz
    tar xzf kafka_2.12-2.3.1.tgz
    ln -s kafka_2.12-2.3.1 kafka

Configure and start Zookeeper

Configure and start the Zookeeper service that manages the Kafka brokers:

  1. On the first instance, configure the Zookeeper ID:
    cd kafka
    mkdir /tmp/zookeeper
    touch /tmp/zookeeper/myid
    echo "1" >> /tmp/zookeeper/myid
  2. Repeat the process on the second instance, using a different ID value:
    cd kafka
    mkdir /tmp/zookeeper
    touch /tmp/zookeeper/myid
    echo "2" >> /tmp/zookeeper/myid
  3. On the first instance, edit the config/zookeeper.properties file, adding the private IP address of the second instance:
    initLimit=5
    syncLimit=2
    tickTime=2000
    # list of servers: <ip>:2888:3888
    server.1=0.0.0.0:2888:3888 
    server.2=<<IP address of second instance>>:2888:3888
    
  4. On the second instance, edit the config/zookeeper.properties file, adding the private IP address of the first instance:
    initLimit=5
    syncLimit=2
    tickTime=2000
    # list of servers: <ip>:2888:3888
    server.1=<<IP address of first instance>>:2888:3888 
    server.2=0.0.0.0:2888:3888
  5. On each instance, start Zookeeper:bin/zookeeper-server-start.sh config/zookeeper.properties

Configure and start Kafka

Configure and start the Kafka broker:

  1. On the first instance, edit the config/server.properties file:
    broker.id=1
    zookeeper.connect=0.0.0.0:2181, =<<IP address of second instance>>:2181
  2. On the second instance, edit the config/server.properties file:
    broker.id=2
    zookeeper.connect=0.0.0.0:2181, =<<IP address of first instance>>:2181
  3. Start Kafka on each instance:
    bin/kafka-server-start.sh config/server.properties

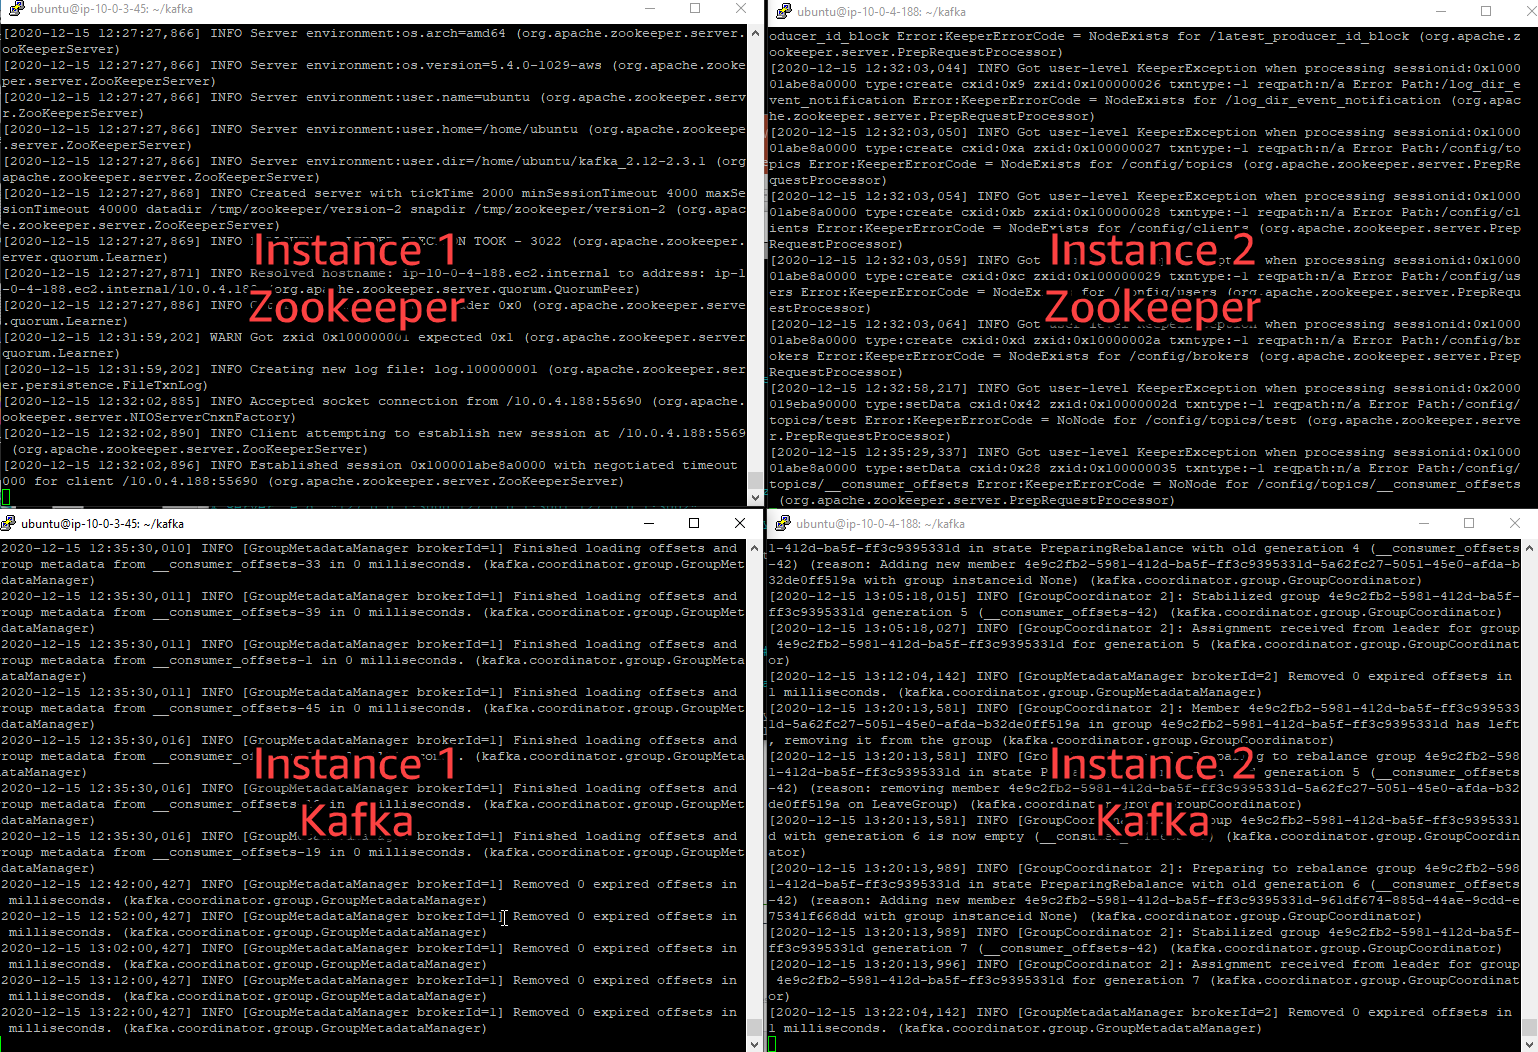
At the end of this process, Zookeeper and Kafka are running on both instances. If you use separate terminals, it looks like this:

Zookeeper and Kafka terminals

Configuring and publishing to a topic

Kafka organizes channels of messages around topics, which are virtual groups of one or many partitions across Kafka brokers in a cluster. Multiple producers can send messages to Kafka topics, which can then be routed to and processed by multiple consumers. Producers publish to the tail of a topic and consumers read the topic at their own pace.

From either of the two instances:

  1. Create a new topic called test:
    bin/kafka-topics.sh --create --bootstrap-server localhost:9092 --replication-factor 2 --partitions 2 --topic test
  2. Start a producer:
    bin/kafka-console-producer.sh --broker-list localhost:9092 –topic
  3. Enter test messages to check for successful publication:Sending messages to the Kafka topic

At this point, you can successfully publish messages to your self-hosted Kafka cluster. Next, you configure a Lambda function as a consumer for the test topic on this cluster.

Configuring the Lambda function and event source mapping

You can create the Lambda event source mapping using the AWS CLI or AWS SDK, which provide the CreateEventSourceMapping API. In this walkthrough, you use the AWS Management Console to create the event source mapping.

Create a Lambda function that uses the self-hosted cluster and topic as an event source:

  1. From the Lambda console, select Create function.
  2. Enter a function name, and select Node.js 12.x as the runtime.
  3. Select the Permissions tab, and select the role name in the Execution role panel to open the IAM console.
  4. Choose Add inline policy and create a new policy called SelfHostedKafkaPolicy with the following permissions. Replace the resource example with the ARNs of your instances:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "ec2:CreateNetworkInterface",
                    "ec2:DescribeNetworkInterfaces",
                    "ec2:DescribeVpcs",
                    "ec2:DeleteNetworkInterface",
                    "ec2:DescribeSubnets",
                    "ec2:DescribeSecurityGroups",
                    "logs:CreateLogGroup",
                    "logs:CreateLogStream",
                    "logs:PutLogEvents"
                ],
                "Resource": " arn:aws:ec2:<REGION>:<ACCOUNT_ID>:instance/<instance-id>"
            }
        ]
    }
    

    Create policy

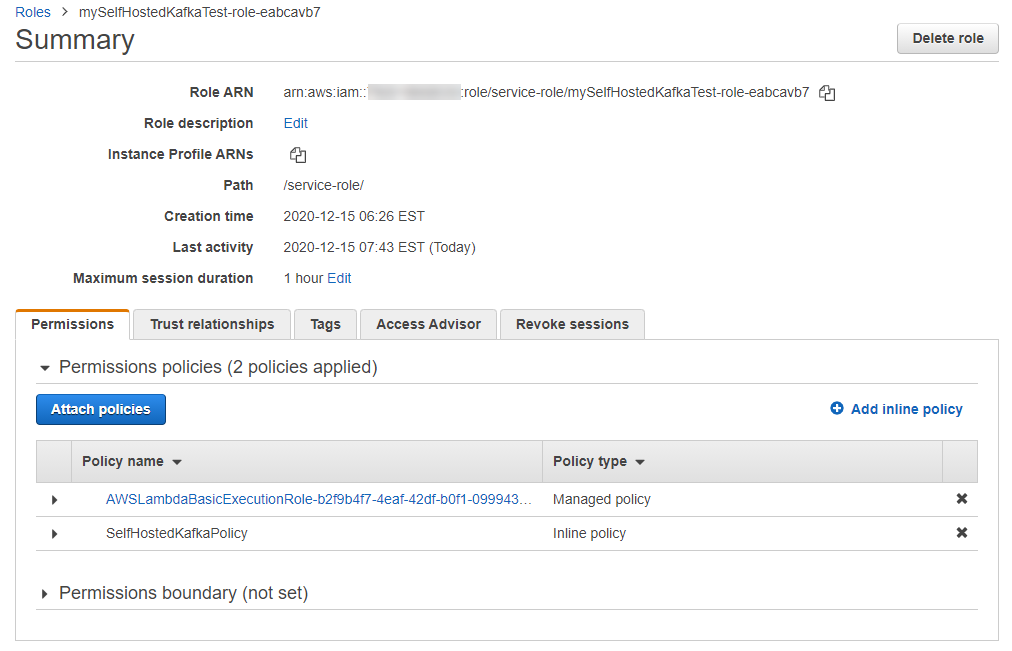
  5. Choose Create policy and ensure that the policy appears in Permissions policies.IAM role page
  6. Back in the Lambda function, select the Configuration tab. In the Designer panel, choose Add trigger.
  7. In the dropdown, select Apache Kafka:
    • For Bootstrap servers, add each of the two instances private IPv4 DNS addresses with port 9092 appended.
    • For Topic name, enter ‘test’.
    • Enter your preferred batch size and starting position values (see this documentation for more information).
    • For VPC, select the VPC created by the template.
    • For VPC subnets, select the two private subnets.
    • For VPC security groups, select the default security group.
    • Choose Add.

Add trigger configuration

The trigger’s status changes to Enabled in the Lambda console after a few seconds. It then takes several minutes for the trigger to receive messages from the Kafka cluster.

Testing the Lambda function

At this point, you have created a VPC with two private and public subnets and a NAT Gateway. You have created a Kafka cluster on two EC2 instances in private subnets. You set up a target Lambda function with the necessary IAM permissions. Next, you publish messages to the test topic in Kafka and see the resulting invocation in the logs for the Lambda function.

  1. In the Function code panel, replace the contents of index.js with the following code and choose Deploy:
    exports.handler = async (event) => {
        // Iterate through keys
        for (let key in event.records) {
          console.log('Key: ', key)
          // Iterate through records
          event.records[key].map((record) => {
            console.log('Record: ', record)
            // Decode base64
            const msg = Buffer.from(record.value, 'base64').toString()
            console.log('Message:', msg)
          }) 
        }
    }
  2. Back in the terminal with the producer script running, enter a test message:Send test message in Kafka
  3. In the Lambda function console, select the Monitoring tab then choose View logs in CloudWatch. In the latest log stream, you see the original event and the decoded message:Log events output

Using Lambda as event source

The Lambda function target in the event source mapping does not need to be connected to a VPC to receive messages from the private instance hosting Kafka. However, you must provide details of the VPC, subnets, and security groups in the event source mapping for the Kafka cluster.

The Lambda function must have permission to describe VPCs and security groups, and manage elastic network interfaces. These execution roles permissions are:

  • ec2:CreateNetworkInterface
  • ec2:DescribeNetworkInterfaces
  • ec2:DescribeVpcs
  • ec2:DeleteNetworkInterface
  • ec2:DescribeSubnets
  • ec2:DescribeSecurityGroups

The event payload for the Lambda function contains an array of records. Each array item contains details of the topic and Kafka partition identifier, together with a timestamp and base64 encoded message:

Event payload example

There is an important difference in the way the Lambda service connects to the self-hosted Kafka cluster compared with Amazon MSK. MSK encrypts data in transit by default so the broker connection defaults to using TLS. With a self-hosted cluster, TLS authentication is not supported when using the Apache Kafka event source. Instead, if accessing brokers over the internet, the event source uses SASL/SCRAM authentication, which can be configured in the event source mapping:

SASL/SCRAM configuration

To learn how to configure SASL/SCRAM authentication your self-hosted Kafka cluster, see this documentation.

Conclusion

Lambda now supports self-hosted Kafka as an event source so you can invoke Lambda functions from messages in Kafka topics to integrate into other downstream serverless workflows.

This post shows how to configure a self-hosted Kafka cluster on EC2 and set up the network configuration. I also cover how to set up the event source mapping in Lambda and test a function to decode the messages sent from Kafka.

To learn more about how to use this feature, read the documentation. For more serverless learning resource, visit Serverless Land.

Creating a cross-region Active Directory domain with AWS Launch Wizard for Microsoft Active Directory

Post Syndicated from AWS Admin original https://aws.amazon.com/blogs/compute/creating-a-cross-region-active-directory-domain-with-aws-launch-wizard-for-microsoft-active-directory/

AWS Launch Wizard is a console-based service to quickly and easily size, configure, and deploy third party applications, such as Microsoft SQL Server Always On and HANA based SAP systems, on AWS without the need to identify and provision individual AWS resources. AWS Launch Wizard offers an easy way to deploy enterprise applications and optimize costs. Instead of selecting and configuring separate infrastructure services, you go through a few steps in the AWS Launch Wizard and it deploys a ready-to-use application on your behalf. It reduces the time you need to spend on investigating how to provision, cost and configure your application on AWS.

You can now use AWS Launch Wizard to deploy and configure self-managed Microsoft Windows Server Active Directory Domain Services running on Amazon Elastic Compute Cloud (EC2) instances. With Launch Wizard, you can have fully-functioning, production-ready domain controllers within a few hours—all without having to manually deploy and configure your resources.

You can use AWS Directory Service to run Microsoft Active Directory (AD) as a managed service, without the hassle of managing your own infrastructure. If you need to run your own AD infrastructure, you can use AWS Launch Wizard to simplify the deployment and configuration process.

In this post, I walk through creation of a cross-region Active Directory domain using Launch Wizard. First, I deploy a single Active Directory domain spanning two regions. Then, I configure Active Directory Sites and Services to match the network topology. Finally, I create a user account to verify replication of the Active Directory domain.

Diagram of Resources deployed in this post

Figure 1: Diagram of resources deployed in this post

Prerequisites

  1. You must have a VPC in your home. Additionally, you must have remote regions that have CIDRs that do not overlap with each other. If you need to create VPCs and subnets that do not overlap, please refer here.
  2. Each subnet used must have outbound internet connectivity. Feel free to either use a NAT Gateway or Internet Gateway.
  3. The VPCs must be peered in order to complete the steps in this post. For information on creating a VPC Peering connection between regions, please refer here.
  4. If you choose to deploy your Domain Controllers to a private subnet, you must have an RDP jump / bastion instance setup to allow you to RDP to your instance.

Deploy Your Domain Controllers in the Home Region using Launch Wizard

In this section, I deploy the first set of domain controllers into the us-east-1 the home region using Launch Wizard. I refer to US-East-1 as the home region, and US-West-2 as the remote region.

  1. In the AWS Launch Wizard Console, select Active Directory in the navigation pane on the left.
  2. Select Create deployment.
  3. In the Review Permissions page, select Next.
  4. In the Configure application settings page set the following:
    • General:
      • Deployment name: UsEast1AD
    • Active Directory (AD) installation
      • Installation type: Active Directory on EC2
    • Domain Settings:
      • Number of domain controllers: 2
      • AMI installation type: License-included AMI
    • License-included AMI: ami-################# | Windows_Server-2019-English-Full-Base-202#-##-##
    • Connection type: Create new Active Directory
    • Domain DNS name: corp.example.com
    • Domain NetBIOS Name: CORP
    • Connectivity:
      • Key Pair Name: Choose and exiting Key pair or select and existing one.
      • Virtual Private Cloud (VPC): Select Virtual Private Cloud (VPC)
    • VPC: Select your home region VPC
    • Availability Zone (AZ) and private subnets:
      • Select 2 Availability Zones
      • Choose the proper subnet in each subnet
      • Assign a Controller IP address for each domain controller
    • Remote Desktop Gateway preferences: Disregard for now, this is set up later.
    • Check the I confirm that a public subnet has been set up. Each of the selected private subnets have outbound connectivity enabled check box.
  1. Select Next.
  2. In the Define infrastructure requirements page, set the following inputs.
    • Storage and compute: Based on infrastructure requirements
    • Number of AD users: Up to 5000 users
  3. Select Next.
  4. In the Review and deploy page, review your selections. Then, select Deploy.

Note that it may take up to 2 hours for your domain to be deployed. Once the status has changed to Completed, you can proceed to the next section. In the next section, I prepare Active Directory Sites and Services for the second set of domain controller in my other region.

Configure Active Directory Sites and Services

In this section, I configure the Active Directory Sites and Services topology to match my network topology. This step ensures proper Active Directory replication routing so that domain clients can find the closest domain controller. For more information on Active Directory Sites and Services, please refer here.

Retrieve your Administrator Credentials from Secrets Manager

  1. From the AWS Secrets Manager Console in us-east-1, select the Secret that begins with LaunchWizard-UsEast1AD.
  2. In the middle of the Secret page, select Retrieve secret value.
    1. This will display the username and password key with their values.
    2. You need these credentials when you RDP into one of the domain controllers in the next steps.

Rename the Default First Site

  1. Log in to the one of the domain controllers in us-east-1.
  2. Select Start, type dssite and hit Enter on your keyboard.
  3. The Active Directory Sites and Services MMC should appear.
    1. Expand Sites. There is a site named Default-First-Site-Name.
    2. Right click on Default-First-Site-Name select Rename.
    3. Enter us-east-1 as the name.
  4. Leave the Active Directory Sites and Services MMC open for the next set of steps.

Create a New Site and Subnet Definition for US-West-2

  1. Using the Active Directory Sites and Services MMC from the previous steps, right click on Sites.
  2. Select New Site… and enter the following inputs:
    • Name: us-west-2
    • Select DEFAULTIPSITELINK.
  3.  Select OK.
  4. A pop up will appear telling you there will need to be some additional configuration. Select OK.
  5. Expand Sites and right click on Subnets and select New Subnet.
  6. Enter the following information:
    • Prefix: the CIDR of your us-west-2 VPC. An example would be 1.0.0/24
    • Site: select us-west-2
  7. Select OK.
  8. Leave the Active Directory Sites and Services MMC open for the following set of steps.

Configure Site Replication Settings

Using the Active Directory Sites and Services MMC from the previous steps, expand Sites, Inter-Site Transports, and select IP. You should see an object named DEFAULTIPSITELINK,

  1. Right click on DEFAULTIPSITELINK.
  2. Select Properties. Set or verify the following inputs on the General tab:
  3. Select Apply.
  4. In the DEFAULTIPSITELINK Properties, select the Attribute Editor tab and modify the following:
    • Scroll down and double click on Enter 1 for the Value, then select OK twice.
      • For more information on these settings, please refer here.
  5. Close the Active Directory Sites and Services MMC, as it is no longer needed.

Prepare Your Home Region Domain Controllers Security Group

In this section, I modify the Domain Controllers Security Group in us-east-1. This allows the domain controllers deployed in us-west-2 to communicate with each other.

  1. From the Amazon Elastic Compute Cloud (Amazon EC2) console, select Security Groups under the Network & Security navigation section.
  2. Select the Domain Controllers Security Group that was created with Launch Wizard Active Directory.
  3. Select Edit inbound rules. The Security Group should start with LaunchWizard-UsEast1AD-.
  4. Choose Add rule and enter the following:
    • Type: Select All traffic
    • Protocol: All
    • Port range: All
    • Source: Select Custom
    • Enter the CIDR of your remote VPC. An example would be 1.0.0/24
  5. Select Save rules.

Create a Copy of Your Administrator Secret in Your Remote Region

In this section, I create a Secret in Secrets Manager that contains the Administrator credentials when I created a home region.

  1. Find the Secret that being with LaunchWizard-UsEast1AD from the AWS Secrets Manager Console in us-east-1.
  2. In the middle of the Secret page, select Retrieve secret value.
    • This displays the username and password key with their values. Make note of these keys and values, as we need them for the next steps.
  3. From the AWS Secrets Manager Console, change the region to us-west-2.
  4. Select Store a new secret. Then, enter the following inputs:
    • Select secret type: Other type of secrets
    • Add your first keypair
    • Select Add row to add the second keypair
  5. Select Next, then enter the following inputs.
    • Secret name: UsWest2AD
    • Select Next twice
    • Select Store

Deploy Your Domain Controllers in the Remote Region using Launch Wizard

In this section, I deploy the second set of domain controllers into the us-west-1 region using Launch Wizard.

  1. In the AWS Launch Wizard Console, select Active Directory in the navigation pane on the left.
  2. Select Create deployment.
  3. In the Review Permissions page, select Next.
  4. In the Configure application settings page, set the following inputs.
    • General
      • Deployment name: UsWest2AD
    • Active Directory (AD) installation
      • Installation type: Active Directory on EC2
    • Domain Settings:
      • Number of domain controllers: 2
      • AMI installation type: License-included AMI
      • License-included AMI: ami-################# | Windows_Server-2019-English-Full-Base-202#-##-##
    • Connection type: Add domain controllers to existing Active Directory
    • Domain DNS name: corp.example.com
    • Domain NetBIOS Name: CORP
    • Domain Administrator secret name: Select you secret you created above.
    • Add permission to secret
      • After you verified the Secret you created above has the policy listed. Check the checkbox confirming the secret has the required policy.
    • Domain DNS IP address for resolution: The private IP of either domain controller in your home region
    • Connectivity:
      • Key Pair Name: Choose an existing Key pair
      • Virtual Private Cloud (VPC): Select Virtual Private Cloud (VPC)
    • VPC: Select your home region VPC
    • Availability Zone (AZ) and private subnets:
      • Select 2 Availability Zones
      • Choose the proper subnet in each subnet
      • Assign a Controller IP address for each domain controller
    • Remote Desktop Gateway preferences: disregard for now, as I set this later.
    • Check the I confirm that a public subnet has been set up. Each of the selected private subnets have outbound connectivity enabled check box
  1. In the Define infrastructure requirements page set the following:
    • Storage and compute: Based on infrastructure requirements
    • Number of AD users: Up to 5000 users
  2. In the Review and deploy page, review your selections. Then, select Deploy.

Note that it may take up to 2 hours to deploy domain controllers. Once the status has changed to Completed, proceed to the next section. In this next section, I prepare Active Directory Sites and Services for the second set of domain controller in another region.

Prepare Your Remote Region Domain Controllers Security Group

In this section, I modify the Domain Controllers Security Group in us-west-2. This allows the domain controllers deployed in us-west-2 to communicate with each other.

  1. From the Amazon Elastic Compute Cloud (Amazon EC2) console, select Security Groups under the Network & Security navigation section.
  2. Select the Domain Controllers Security Group that was created by your Launch Wizard Active Directory.
  3. Select Edit inbound rules. The Security Group should start with LaunchWizard-UsWest2AD-EC2ADStackExistingVPC-
  4. Choose Add rule and enter the following:
    • Type: Select All traffic
    • Protocol: All
    • Port range: All
    • Source: Select Custom
    • Enter the CIDR of your remote VPC. An example would be 0.0.0/24
  5. Choose Save rules.

Create an AD User and Verify Replication

In this section, I create a user in one region and verify that it replicated to the other region. I also use AD replication diagnostics tools to verify that replication is working properly.

Create a Test User Account

  1. Log in to one of the domain controllers in us-east-1.
  2. Select Start, type dsa and press Enter on your keyboard. The Active Directory Users and Computers MMC should appear.
  3. Right click on the Users container and select New > User.
  4. Enter the following inputs:
    • First name: John
    • Last name: Doe
    • User logon name: jdoe and select Next
    • Password and Confirm password: Your choice of complex password
    • Uncheck User must change password at next logon
  5. Select Next.
  6. Select Finish.

Verify Test User Account Has Replicated

  1. Log in to the one of the domain controllers in us-west-2.
  2. Select Start and type dsa.
  3. Then, press Enter on your keyboard. The Active Directory Users and Computers MMC should appear.
  4. Select Users. You should see a user object named John Doe.

Note that if the user is not present, it may not have been replicated yet. Replication should not take longer than 60 seconds from when the item was created.

Summary

Congratulations, you have created a cross-region Active Directory! In this post you:

  1. Launched a new Active Directory forest in us-east-1 using AWS Launch Wizard.
  2. Configured Active Directory Sites and Service for a multi-region configuration.
  3. Launched a set of new domain controllers in the us-west-2 region using AWS Launch Wizard.
  4. Created a test user and verified replication.

This post only touches on a couple of features that are available in the AWS Launch Wizard Active Directory deployment. AWS Launch Wizard also automates the creation of a Single Tier PKI infrastructure or trust creation. One of the prime benefits of this solution is the simplicity in deploying a fully functional Active Directory environment in just a few clicks. You no longer need to do the undifferentiated heavy lifting required to deploy Active Directory.  For more information, please refer to AWS Launch Wizard documentation.

Announcing Amazon Managed Service for Grafana (in Preview)

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/announcing-amazon-managed-grafana-service-in-preview/

Today, in partnership with Grafana Labs, we are excited to announce in preview, Amazon Managed Service for Grafana (AMG), a fully managed service that makes it easy to create on-demand, scalable, and secure Grafana workspaces to visualize and analyze your data from multiple sources.

Grafana is one of the most popular open source technologies used to create observability dashboards for your applications. It has a pluggable data source model and support for different kinds of time series databases and cloud monitoring vendors. Grafana centralizes your application data from multiple open-source, cloud, and third-party data sources.

Many of our customers love Grafana, but don’t want the burden of self-hosting and managing it. AMG manages the provisioning, setup, scaling, version upgrades and security patching of Grafana, eliminating the need for customers to do it themselves. AMG automatically scales to support thousands of users with high availability.

With AMG, you will get a fully managed and secure data visualization service where you can query, correlate, and visualize operational metrics, logs and traces across multiple data sources including cloud services such as AWS, Google, and Microsoft. AMG is integrated with AWS data sources, such as Amazon CloudWatch, Amazon Elasticsearch Service, AWS X-Ray, AWS IoT SiteWise, Amazon Timestream, and others to collect operational data in a simple way. Additionally, AMG also provides plug-ins to connect to popular third-party data sources, such as Datadog, Splunk, ServiceNow, and New Relic by upgrading to Grafana Enterprise directly from the AWS Console.

Screenshot for creating and configuring a managed Grafana workspace

AMG integrates directly into your AWS Organizations. You can define a AMG workspace in one AWS account that allows you to discover and access datasources in all your accounts and regions across your AWS organization. Creating dashboards in Grafana is easy as all these different datasources are discoverable in one place.

Customers really like Grafana for the ease of creating dashboards, it comes with many built-in dashboards to use when you add a new data source, or you can take advantage of its broad community of pre-built dashboards. For example, you can see in the following image a really nice dashboard that AMG created for me from one of my AWS Lambda function.

Screenshot of an automatic dashboard for Lambda function

One of my favorite things from AMG is the built-in security features. You can easily enable single sign-on using AWS Single Sign-On, restrict access to data sources and dashboards to the right users, and access audit logs via AWS CloudTrail for your hosted Grafana workspace. With AWS Single Sign-On you can leverage your existing corporate directories to enforce authentication and authorization permissions.

Another powerful feature that AMG has is support for Alerts. AMG integrates with Amazon Simple Notification Service (SNS) so customers can send Grafana alerts to SNS as a notification destination. It also has support for four other alert destinations including PagerDuty, Slack, VictorOps and OpsGenie.

There are no up-front investments required to use AMG, and you only pay a monthly active user license fee. This means that you can provision many users to access to your Grafana workspace, but will only be billed for active users that log in and use the workspace that month. Users granted access but that do not log in, will not be billed that month. You can also upgrade to Grafana Enterprise using AWS Marketplace, to get access to enterprise plugins, support, and training content directly from Grafana Labs.

Availability

This service is available in US East (N. Virginia) and Europe (Ireland) regions. To learn more visit the AMG service page, and be sure to join our re:Invent session tomorrow 12/16 from 8:00am – 8:30am PST for a demo!

AMG is now available in preview; to get access to this service fill out the registration form here.

— Marcia

New – AWS Systems Manager Consolidates Application Management

Post Syndicated from Steve Roberts original https://aws.amazon.com/blogs/aws/new-aws-systems-manager-consolidates-application-management/

A desire for consolidated, and simplified operational oversight isn’t limited to just cloud infrastructure. Increasingly, customers ask us for a “single pane of glass” approach for also monitoring and managing their application portfolios.

These customers tell us that detection and investigation of application issues takes additional time and effort, due to the typical use of multiple consoles, tools, and sources of information such as resource usage metrics, logs, and more, to enable their DevOps engineers to obtain context about the application issue under investigation. Here, an “application” means not just the application code but also the logical group of resources that act as a unit to host the application, along with ownership boundaries for operators, and environments such as development, staging, and production.

Today, I’m pleased to announce a new feature of AWS Systems Manager, called Application Manager. Application Manager aggregates operational information from multiple AWS services and Systems Manager capabilities into a single console, making it easier to view operational data for your applications.

To make it even more convenient, the service can automatically discover your applications. Today, auto-discovery is available for applications running in AWS CloudFormation stacks and Amazon Elastic Kubernetes Service (EKS) clusters, or launched using AWS Launch Wizard. Applications can also be discovered from Resource Groups.

A particular benefit of automated discovery is that application components and resources are automatically kept up-to-date on an ongoing basis, but you can also always revise applications as needed by adding or deleting components manually.

With applications discovered and consolidated into a single console, you can more easily diagnose operational issues and resolve them with minimal time and effort. Automated runbooks targeting an application component or resource can be run to help remediate operational issues. For any given application, you can select a resource and explore relevant details without needing to leave the console.

For example, the application can surface Amazon CloudWatch logs, operational metrics, AWS CloudTrail logs, and configuration changes, removing the need to engage with multiple tools or consoles. This means your on-call engineers can understand issues more quickly and reduce the time needed to resolve them.

Exploring an Application with Application Manager
I can access Application Manager from the Systems Manager home page. Once open, I get an overview of my discovered applications and can see immediately that there are some alarms, without needing to switch context to the Amazon CloudWatch console, and some operations items (“OpsItems”) that I might need to pay attention to. I can also switch to the Applications tab to view the collections of applications, or I can click the buttons in the Applications panel for the collection I’m interested in.

Screenshot of the <span title="">Application Manager</span> overview page

In the screenshot below, I’ve navigated to a sample application and again, have indicators showing that alarms have raised. The various tabs enable me to drill into more detail to view resources used by the application, config resource and rules compliance, monitoring alarms, logs, and automation runbooks associated with the application.

Screenshot of application components and overview

Clicking on the Alarm indicator takes me into the Monitoring tab, and it shows that the ConsumedWriteCapacityUnits alarm has been raised. I can change the timescale to zero in on when the event occurred, or I can use the View recent alarms dashboard link to jump into the Amazon CloudWatch Alarms console to view more detail.

Screenshot of alarms on the <span title="">Application Manager</span> Monitoring tab

The Logs tab shows me a consolidated list of log groups for the application, and clicking a log group name takes me directly to the CloudWatch Logs where I can inspect the log streams, and take advantage of Log Insights to dive deeper by querying the log data.

OpsItems shows me operational issues associated with the resources of my application, and enables me to indicate the current status of the issue (open, in progress, resolved). Below, I am marking investigation of a stopped EC2 instance as in progress.

Screenshot of <span title="">Application Manager</span> OpsItems tab

Finally, Runbooks shows me automation documents associated with the application and their execution status. Below, it’s showing that I ran the AWS-RestartEC2Instance automation document to restart the EC2 instance that was stopped, and I would now resolve the issue logged in the OpsItems tab.

Screenshot of <span title="">Application Manager</span>'s Runbooks tab

Consolidating this information into a single console gives engineers a single starting location to monitor and investigate issues arising with their applications, and automatic discovery of applications and resources makes getting started simple. AWS Systems Manager Application Manager is available today, at no extra charge, in all public AWS Regions where Systems Manager is available.

Learn more about Application Manager and get started at AWS Systems Manager.

— Steve

New – AWS Systems Manager Fleet Manager

Post Syndicated from Steve Roberts original https://aws.amazon.com/blogs/aws/new-aws-systems-manager-fleet-manager/

Organizations, and their systems administrators, routinely face challenges in managing increasingly diverse portfolios of IT infrastructure across cloud and on-premises environments. Different tools, consoles, services, operating systems, procedures, and vendors all contribute to complicate relatively common, and related, management tasks. As workloads are modernized to adopt Linux and open-source software, those same systems administrators, who may be more familiar with GUI-based management tools from a Windows background, have to continually adapt and quickly learn new tools, approaches, and skill sets.

AWS Systems Manager is an operational hub enabling you to manage resources on AWS and on-premises. Available today, Fleet Manager is a new console based experience in Systems Manager that enables systems administrators to view and administer their fleets of managed instances from a single location, in an operating-system-agnostic manner, without needing to resort to remote connections with SSH or RDP. As described in the documentation, managed instances includes those running Windows, Linux, and macOS operating systems, in both the AWS Cloud and on-premises. Fleet Manager gives you an aggregated view of your compute instances regardless of where they exist.

All that’s needed, whether for cloud or on-premises servers, is the Systems Manager agent installed on each server to be managed, some AWS Identity and Access Management (IAM) permissions, and AWS Key Management Service (KMS) enabled for Systems Manager‘s Session Manager. This makes it an easy and cost-effective approach for remote management of servers running in multiple environments without needing to pay the licensing cost of expensive management tools you may be using today. As noted earlier, it also works with instances running macOS. With the agent software and permissions set up, Fleet Manager enables you to explore and manage your servers from a single console environment. For example, you can navigate file systems, work with the registry on Windows servers, manage users, and troubleshoot logs (including viewing Windows event logs) and monitor common performance counters without needing the Amazon CloudWatch agent to be installed.

Exploring an Instance With Fleet Manager
To get started exploring my instances using Fleet Manager, I first head to the Systems Manager console. There, I select the new Fleet Manager entry on the navigation toolbar. I can also select the Managed Instances option – Fleet Manager replaces Managed Instances going forward, but the original navigation toolbar entry will be kept for backwards compatibility for a short while. But, before we go on to explore my instances, I need to take you on a brief detour.

When you select Fleet Manager, as with some other views in Systems Manager, a check is performed to verify that a role, named AmazonSSMRoleForInstancesQuickSetup, exists in your account. If you’ve used other components of Systems Manager in the past, it’s quite possible that it does. The role is used to permit Systems Manager to access your instances on your behalf and if the role exists, then you’re directed to the requested view. If however the role doesn’t exist, you’ll first be taken to the Quick Setup view. This in itself will trigger creation of the role, but you might want to explore the capabilities of Quick Setup, which you can also access any time from the navigation toolbar.

Quick Setup is a feature of Systems Manager that you can use to set up specific configuration items, such as the Systems Manager and CloudWatch agents on your instances (and keep them up-to-date), and also IAM roles permitting access to your resources for Systems Manager components. For this post, all the instances I’m going to use already have the required agent set up, including the role permissions, so I’m not going to discuss this view further but I encourage you to check it out. I also want to remind you that to take full advantage of Fleet Manager‘s capabilities you first need to have KMS encryption enabled for your instances and secondly, the role attached to your Amazon Elastic Compute Cloud (EC2) instances must have the kms:Decrypt role permission included, referencing the key you selected when you enabled KMS encryption. You can enable encryption, and select the KMS key, using the Preferences section of the Session Manager console, and of course you can set up the role permission in the IAM console.

That’s it for the diversion; if you have the role already, as I do, you’ll now be at the Managed instances list view. If you’re at Quick Setup instead, simply click the Fleet Manager navigation button once more.

The Managed instances view shows me all of my instances, in the cloud or on-premises, that I can access. Selecting an instance, in this case an EC2 Windows instance launched using AWS Elastic Beanstalk, and clicking Instance actions presents me with a menu of options. The options (less those specific to Windows) are available for my Amazon Linux instance too, and for instances running macOS I can use the View file system option.

Screenshot of <span title="">Fleet Manager</span>'s Managed instances view

The File system view displays a read-only view onto the file system of the selected instance. This can be particularly useful for viewing text-based log files, for example, where I can preview up to 10,000 lines of a log file and even tail it to view changes as the log updates. I used this to open and tail an IIS web server log on my Windows Server instance. Having selected the instance, I next select View file system from the Instance actions dropdown (or I can click the Instance ID to open a view onto that instance and select File system from the menu displayed on the instance view).

Having opened the file system view for my instance, I navigate to the folder on the instance containing the IIS web server logs.

Screenshot of <span title="">Fleet Manager</span>'s File system view

Selecting a log file, I then click Actions and select Tail file. This opens a view onto the log file contents, which updates automatically as new content is written.

Screenshot of tailing a log file in <span title="">Fleet Manager</span>

As I mentioned, the File system view is also accessible for macOS-based instances. For example, here is a screenshot of viewing the Applications folder on an EC2 macOS instance.

Screenshot of macOS file system view in <span title="">Fleet Manager</span>

Next, let’s examine the Performance counters view, which is available for both Windows and Linux instances. This view displays CPU, memory, network traffic, and disk I/O and will be familiar to Windows users from Task Manager. The metrics shown reflect the guest OS metrics, whereas EC2 instance metrics you may be used to relate to the hypervisor. On this particular instance I’ve deployed an ASP.NET Core 5 application, which generates a varying length collection of Fibonacci numbers on page refresh. Below is a snapshot of the counters, after I’ve put the instance under a small amount of load. The view updates automatically every 5 seconds.

Screenshot of <span title="">Fleet Manager</span>'s Performance Counters view

There are more views available than I have space for in this post. Using the Windows Registry view, I can view and edit the registry on the selected Windows instance. Windows event logs gives me access to the Application and Service logs, and common Windows logs such as System, Setup, Security, etc. With Users and groups I can manage users or groups, including assignment of users to groups (again for both Windows and Linux instances). For all views, Fleet Manager enables me to use a single and convenient console.

Getting Started
AWS Systems Manager Fleet Manager is available today for use with managed instances running Windows, Linux, and macOS. Information on pricing, for this and other Systems Manager features, can be found at this page.

Learn more, and get started with Fleet Manager today, at AWS Systems Manager.

— Steve

Introducing AWS Systems Manager Change Manager

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/introducing-systems-manager-change-manager/

Because you are constantly listening to the feedback from your customer, you are iterating, innovating, and improving your applications and infrastructures. You continually modify your IT systems in the cloud. And let’s face it, changing something in a working system risks breaking things or introducing side effects that are sometimes unpredictable; it doesn’t matter how many tests you do. On the other hand, not making changes is stasis, followed by irrelevance, followed by death.

This is why organizations of all sizes and types have embraced a culture of controlling changes. Some organizations adopt change management processes such as the ones defined in ITIL v4. Some have adopted DevOps’ Continuous Deployment, or other methods. In any case, to support your change management processes, it is important to have tools.

Today, we are launching AWS Systems Manager Change Manager, a new change management capability for AWS Systems Manager. It simplifies the way ops engineers track, approve, and implement operational changes to their application configurations and infrastructures.

Using Change Manager has two primary advantages. First, it can improve the safety of changes made to application configurations and infrastructures, reducing the risk of service disruptions. It makes operational changes safer by tracking that only approved changes are being implemented. Secondly, it is tightly integrated with other AWS services, such as AWS Organizations and AWS Single Sign-On, or the integration with the Systems Manager change calendar and Amazon CloudWatch alarms.

Change Manager provides accountability with a consistent way to report and audit changes made across your organization, their intent, and who approved and implemented them.

Change Manager works across AWS Regions and multiple AWS accounts. It works closely with Organizations and AWS SSO to manage changes from a central point and to deploy them in a controlled way across your global infrastructure.

Terminology
You can use AWS Systems Manager Change Manager on a single AWS account, but most of the time, you will use it in a multi-account configuration.

The way you manage changes across multiple AWS accounts depends on how these accounts are linked together. Change Manager uses the relationships between your accounts defined in AWS Organizations. When using Change Manager, there are three types of accounts:

  • The management account – also known as the “main account” or “root account.” The management account is the root account in an AWS Organizations hierarchy. It is the management account by virtue of this fact.
  • The delegated administrator account – A delegated administrator account is an account that has been granted permission to manage other accounts in Organizations. In the Change Manager context, this is the account from which change requests will be initiated. You will typically log in to this account to manage templates and change requests. Using a delegated administrators account allows you to limit connections made to the root account. It also allows you to enforce a least privileges policy by using a specific subset of permissions required by the changes.
  • The member accounts – Member accounts are accounts that are not the management account or a delegated administrator account, but are still included in Organizations. In my mental model for Change Manager, these would be the accounts that hold the resources where changes are deployed. A delegated administrator account would initiate a change request that would impact resources in a member account. System administrators are discouraged from logging directly into these accounts.

Let’s see how you can use AWS Systems Manager Change Manager by taking a short walk-through demo.

One-Time Configuration
In this scenario, I show you how to use Change Manager with multiple AWS accounts linked together with Organizations. If you are not interested in the one-time configuration, jump to the Create a Change Request section below.

There are four one-time configuration actions to take before using Change Manager: one action in the root account and three in the delegated administrator account. In the root account, I use Quick Setup to define my delegated administrator account and initially configure permissions on the accounts. In the delegated administrator account, you define your source of user identities, you define what users have permissions to approve change templates, and you define a change request template.

First, I ensure I have an Organization in place and my AWS accounts are organized in Organizational Units (OU). For the purpose of this simple example, I have three accounts: the root account, the delegated administrator account in the management OU and a member account in the managed OU. When ready, I use Quick Setup on the root account to configure my accounts. There are multiple paths leading to Quick Setup; for this demo, I use the blue banner on top of the Quick Setup console, and I click Setup Change Manager.

Change Manager Quick Setup


On the Quick Setup page, I enter the ID of the delegated administrator account if I haven’t defined it already. Then I choose the permissions boundaries I grant to the delegated administrator account to perform changes on my behalf. This is the maximum permissions Change Manager receives to make changes. I will further restrict this permission set when I create change requests in a few minutes. In this example, I grant Change Manager permissions to call any ec2 API. This effectively authorizes Change Manager to only run changes related to EC2 instances.

Change Manager Quick Setup

Lower on the screen, I choose the set of accounts that are targets for my changes. I choose between Entire organization or Custom to select one or multiple OUs.

Change Manager Quick Setup 2

After a while, Quick Setup finishes configuring my AWS accounts permission and I can move to the second part of the one-time setup.

Change Manager Quick Setup 3

Second, I switch to my delegated administrator account. Change Manager asks me how I manage users in my organization: with AWS Identity and Access Management (IAM) or AWS Single Sign-On? This defines where Change Manager pulls user identities when I choose approvers. This is a one-time configuration option. This can be changed at any time in the Change Manager Settings page.

Change Manager Settings

Third, on the same page, I define an Amazon Simple Notification Service (SNS) topic to receive notifications about template reviews. This channel is notified any time a template is created or modified, to let template approvers review and approve templates. I also define the IAM (or SSO) user with permission to approve change templates (more about these in one minute).

Change Manager Template Reviewers

Optionally, you can use the existing AWS Systems Manager Change Calendar to define the periods where changes are not authorized, such as marketing events or holiday sales.

Finally, I define a change template. Every change request is created from a template. Templates define common parameters for all change requests based on them, such as the change request approvers, the actions to perform, or the SNS topic to send notifications of progress. You can enforce the review and approval of templates before they can be used. It makes sense to create multiple templates to handle different type of changes. For example, you can create one template for standard changes, and one for emergency changes that overrides the change calendar. Or you can create different templates for different types of automation run books (documents).

To help you to get started, we created a template for you: the “Hello World” template. You can use it as a starting point to create a change request and test out your approval flow.

At any time, I can create my own template. Let’s imagine my system administrator team is frequently restarting EC2 instances. I create a template allowing them to create change requests to restart one or multiple instances. Using the delegated administrator account, I navigate to the Change Manager management console and click Create template.

Change Manager Create Template

In a nutshell, a template defines the list of authorized actions, where to send notifications and who can approve the change request. Actions are an AWS Systems Manager runbook. Emergency change templates allow change requests to bypass the change calendar I wrote about earlier. Under Runbook Options, I choose one or multiple runbooks allowed to run. For this example, I choose the AWS EC2RestartInstance runbook.

I use the console to create the template, but templates are defined internally as YAML. I can edit the YAML using the Editor tab, or when I am using the AWS Command Line Interface (CLI) or API. This means I can version control them just like the rest of my infrastructure (as code).Change Manager Create Template part 1

Just below, I document my template using text formatted as markdown format. I use this section to document the defining characteristics of the template and provide any necessary instructions, such as back-out procedures, to the requestor.

Change Manager Template Documentation

I scroll down that page and click Add Approver to define approvers. Approvers can be individual users or groups. The list of approvers are defined either at the template level or in the change request itself. I also choose to create an SNS topic to inform approvers when any requests are created that require their approval.

In the Monitoring section I select the alarm that, when active, stops any change based on this template, and initiate a rollback.

In the Notifications section, I select or create another SNS topic so I’m notified when status changes for this template occur.

Change Manager Create Template part 2

Once I am done, I save the template and submit it for review.

Change Manager Submit Template for Review

Templates have to be reviewed and approved before they can be used. To approve the template, I connect the console as the template_approver user I defined earlier. As template_approver user, I see pending approvals on the Overview tab. Or, I navigate to the Templates tab, select the template I want to review. When I am done reviewing it, I click Approve.

Change Manager Approve Template

Voila, now we’re ready to create change requests based on this template. Remember that all the preceding steps are one-time configurations and can be amended at any time. When existing templates are modified, the changes go through a review and approval process again.

Create a Change Request
To create a change request on any account linked to the Organization, I open a AWS Systems Manager Change Manager console from the delegated administrator account and click Create request.

Change Manager Create Request

I choose the template I want to use and click Next.

Change Manager Select Template I enter a name for this change request. The change is initiated immediately after all approvals are granted, or I specify an optional scheduled time. When the template allows me, I choose the approver for this change. In this example, the approver is defined by the template and cannot be changed. I click Next.

Change Manager Create CR part 1

On the next screen, there are multiple important configuration options, relating to the actual execution of the change:

  • Target location – lets me define on which target AWS accounts and AWS Region I want to run this change.
  • Deployment target – lets me define which resources are the target of this change. One EC2 instance? Or multiple ones identified by their tags, their resources groups, a list of instance IDs, or all EC2 instances.
  • Runbook parameters – lets me define the parameters I want to pass to my runbook, if any.
  • Execution role – lets me define the set of permissions I grant the System Manager to deploy with this change. The permission set must have service changemanagement.ssm.amazonaws.com as principal for the trust policy. Selecting a role allows me to grant the Change Manager runtime a different permission set than the one I have.

Here is an example allowing Change Manager to stop an EC2 instance (you can scope it down to a specific AWS account, specific Region, or specific instances):

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "ec2:StartInstances",
                "ec2:StopInstances"
            ],
            "Resource": "*",
        },
        {
            "Effect": "Allow",
            "Action": "ec2:DescribeInstances",
            "Resource": "*"
        }
    ]
}

And the associated trust policy:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "Service": "changemanagement.ssm.aws.internal"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}

When I am ready, I click Next. On the last page, I review my data entry and click Submit for approval.

At this stage, the approver receives a notification, based on the SNS topic configured in the template. To continue this demo, I sign out of the console and sign in again as the cr_approver user, which I created, with permission to view and approve change requests.

As the cr_approver user, I navigate to the console, review the change request, and click Approve.

Change Manager Review Change Request

The change request status switches to scheduled, and eventually turns green to Success. At any time, I can click the change request to get the status, and to collect errors, if any.

Change Manager Dashboard with Succeeded Request

I click on the change request to see the details. In particular, the Timeline tab shows the history of this CR.

Change Management CR Timeline

Availability and Pricing
AWS Systems Manager Change Manager is available today in all commercial AWS Regions, except mainland China. The pricing is based on two dimensions: the number of change requests you submit and the total number of API calls made. The number of change requests you submit will be the main cost factor. We will charge $0.29 per change request. Check the pricing page for more details.

You can evaluate Change Manager for free for 30 days, starting on your first change request.

As usual, let us know what you think and let’s get started today

— seb

AWS CloudShell – Command-Line Access to AWS Resources

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/aws-cloudshell-command-line-access-to-aws-resources/

No matter how much automation you have built, no matter how great you are at practicing Infrastructure as Code (IAC), and no matter how successfully you have transitioned from pets to cattle, you sometimes need to interact with your AWS resources at the command line. You might need to check or adjust a configuration file, make a quick fix to a production environment, or even experiment with some new AWS services or features.

Some of our customers feel most at home when working from within a web browser and have yet to set up or customize their own command-line interface (CLI). They tell is that they don’t want to deal with client applications, public keys, AWS credentials, tooling, and so forth. While none of these steps are difficult or overly time-consuming, they do add complexity and friction and we always like to help you to avoid both.

Introducing AWS CloudShell
Today we are launching AWS CloudShell, with the goal of making the process of getting to an AWS-enabled shell prompt simple and secure, with as little friction as possible. Every shell environment that you run with CloudShell has the AWS Command Line Interface (CLI) (v2) installed and configured so you can run aws commands fresh out of the box. The environments also include the Python and Node runtimes, with many more to come in the future.

To get started, I simply click the CloudShell icon in the AWS Management Console:

My shell sets itself up in a matter of seconds and I can issue my first aws command immediately:

The shell environment is based on Amazon Linux 2. I can store up to 1 GB of files per region in my home directory and they’ll be available each time I open a shell in the region. This includes shell configuration files such as .bashrc and shell history files.

I can access the shell via SSO or as any IAM principal that can login to the AWS Management Console, including federated roles. In order to access CloudShell, the AWSCloudShellFullAccess policy must be in effect. The shell runs as a normal (non-privileged) user, but I can sudo and install packages if necessary.

Here are a couple of features that you should know about:

Themes & Font Sizes – You can switch between light and dark color themes, and choose any one of five font sizes:

Tabs and Sessions – You can have multiple sessions open within the same region, and you can control the tabbing behavior, with options to split horizontally and vertically:

You can also download files from the shell environment to your desktop, and upload them from your desktop to the shell.

Things to Know
Here are a couple of important things to keep in mind when you are evaluating CloudShell:

Timeouts & Persistence – Each CloudShell session will timeout after 20 minutes or so of inactivity, and can be reestablished by refreshing the window:

Regions – CloudShell is available today in the US East (N. Virginia), US East (Ohio), US West (Oregon), Europe (Ireland), and Asia Pacific (Tokyo) Regions, with the remaining regions on the near-term roadmap.

Persistent Storage – Files stored within $HOME persist between invocations of CloudShell with a limit of 1 GB per region; all other storage is ephemeral. This means that any software that is installed outside of $HOME will not persist, and that no matter what you change (or break), you can always begin anew with a fresh CloudShell environment.

Network Access – Sessions can make outbound connections to the Internet, but do not allow any type of inbound connections. Sessions cannot currently connect to resources inside of private VPC subnets, but that’s also on the near-term roadmap.

Runtimes – In addition to the Python and Node runtimes, Bash, PowerShell, jq, git, the ECS CLI, the SAM CLI, npm, and pip already installed and ready to use.

Pricing – You can use up to 10 concurrent shells in each region at no charge. You only pay for other AWS resources you use with CloudShell to create and run your applications.

Try it Out
AWS CloudShell is available now and you can start using it today. Launch one and give it a try, and let us know what you think!

— Jeff;

re:Invent 2020 Liveblog: Werner Vogels Keynote

Post Syndicated from AWS News Blog Team original https://aws.amazon.com/blogs/aws/reinvent-2020-liveblog-werner-vogels-keynote/

Join us Tuesday, Dec. 15 for Dr. Werner Vogels’ Keynote as he shares how Amazon is solving today’s hardest technology problems. Jeff Barr, Martin Beeby, Steve Roberts and Channy Yun will liveblog the event, sharing all the highlights, insights and major announcements from this final keynote of re:Invent 2020.

See you here Tuesday, 7:30-10:00 AM (PST)!