Tag Archives: Durable Objects

Our container platform is in production. It has GPUs. Here’s an early look

Post Syndicated from Brendan Irvine-Broque original https://blog.cloudflare.com/container-platform-preview

We’ve been working on something new — a platform for running containers across Cloudflare’s network. We already use it in production for Workers AI, Workers Builds, Remote Browsing Isolation, and the Browser Rendering API. Today, we want to share an early look at how it’s built, why we built it, and how we use it ourselves.

In 2024, Cloudflare Workers celebrates its 7th birthday. When we first announced Workers, it was a completely new model for running compute in a multi-tenant way — on isolates, as opposed to containers. While, at the time, Workers was a pretty bare-bones functions-as-a-service product, we took a big bet that this was going to become the way software was going to be written going forward. Since introducing Workers, in addition to expanding our developer products in general to include storage and AI, we have been steadily adding more compute capabilities to Workers:

2020

Cron Triggers

2021

Durable Objects

Write Workers in Rust

Service Bindings

2022

Queues

Email Workers

Durable Objects Alarms

2023

Workers TCP Socket API 

Hyperdrive

Smart Placement

Workers AI

2024

Python Workers

JavaScript-native RPC

Node.js compatibility

SQLite in Durable Objects

With each of these, we’ve faced a question — can we build this natively into the platform, in a way that removes, rather than adds complexity? Can we build it in a way that lets developers focus on building and shipping, rather than managing infrastructure, so that they don’t have to be a distributed systems engineer to build distributed systems?

In each instance, the answer has been YES. We try to solve problems in a way that simplifies things for developers in the long run, even if that is the harder path for us to take ourselves. If we didn’t, you’d be right to ask — why not self-host and manage all of this myself? What’s the point of the cloud if I’m still provisioning and managing infrastructure? These are the questions many are asking today about the earlier generation of cloud providers.

Pushing ourselves to build platform-native products and features helped us answer this question. Particularly because some of these actually use containers behind the scenes, even though as a developer you never interact with or think about containers yourself.

If you’ve used AI inference on GPUs with Workers AI, spun up headless browsers with Browser Rendering, or enqueued build jobs with the new Workers Builds, you’ve run containers on our network, without even knowing it. But to do so, we needed to be able to run untrusted code across Cloudflare’s network, outside a v8 isolate, in a way that fits what we promise:

  1. You shouldn’t have to think about regions or data centers. Routing, scaling, load balancing, scheduling, and capacity are our problem to solve, not yours, with tools like Smart Placement.

  2. You should be able to build distributed systems without being a distributed systems engineer.

  3. Every millisecond matters — Cloudflare has to be fast.

There wasn’t an off-the-shelf container platform that solved for what we needed, so we built it ourselves — from scheduling to IP address management, pulling and caching images, to improving startup times and more. Our container platform powers many of our newest products, so we wanted to share how we built it, optimized it, and well, you can probably guess what’s next.

Global scheduling — “The Network is the Computer”

Cloudflare serves the entire world — region: earth. Rather than asking developers to provision resources in specific regions, data centers and availability zones, we think “The Network is the Computer”. When you build on Cloudflare, you build software that runs on the Internet, not just in a data center.

When we started working on this, Cloudflare’s architecture was to just run every service via systemd on every server (we call them “metals” — we run our own hardware), allowing all services to take advantage of new capacity we add to our network. That fits running NGINX and a few dozen other services, but cannot fit a world where we need to run many thousands of different compute heavy, resource hungry workloads. We’d run out of space just trying to load all of them! Consider a canonical AI workload — deploying Llama 3.1 8B to an inference server. If we simply ran a Llama 3.1 8B service on every Cloudflare metal, we’d have no flexibility to use GPUs for the many other models that Workers AI supports.

We needed something that would allow us to still take advantage of the full capacity of Cloudflare’s entire network, not just the capacity of individual machines. And ideally not put that burden on the developer.

The answer: we built a control plane on our own Developer Platform that lets us schedule a container anywhere on Cloudflare’s Network:
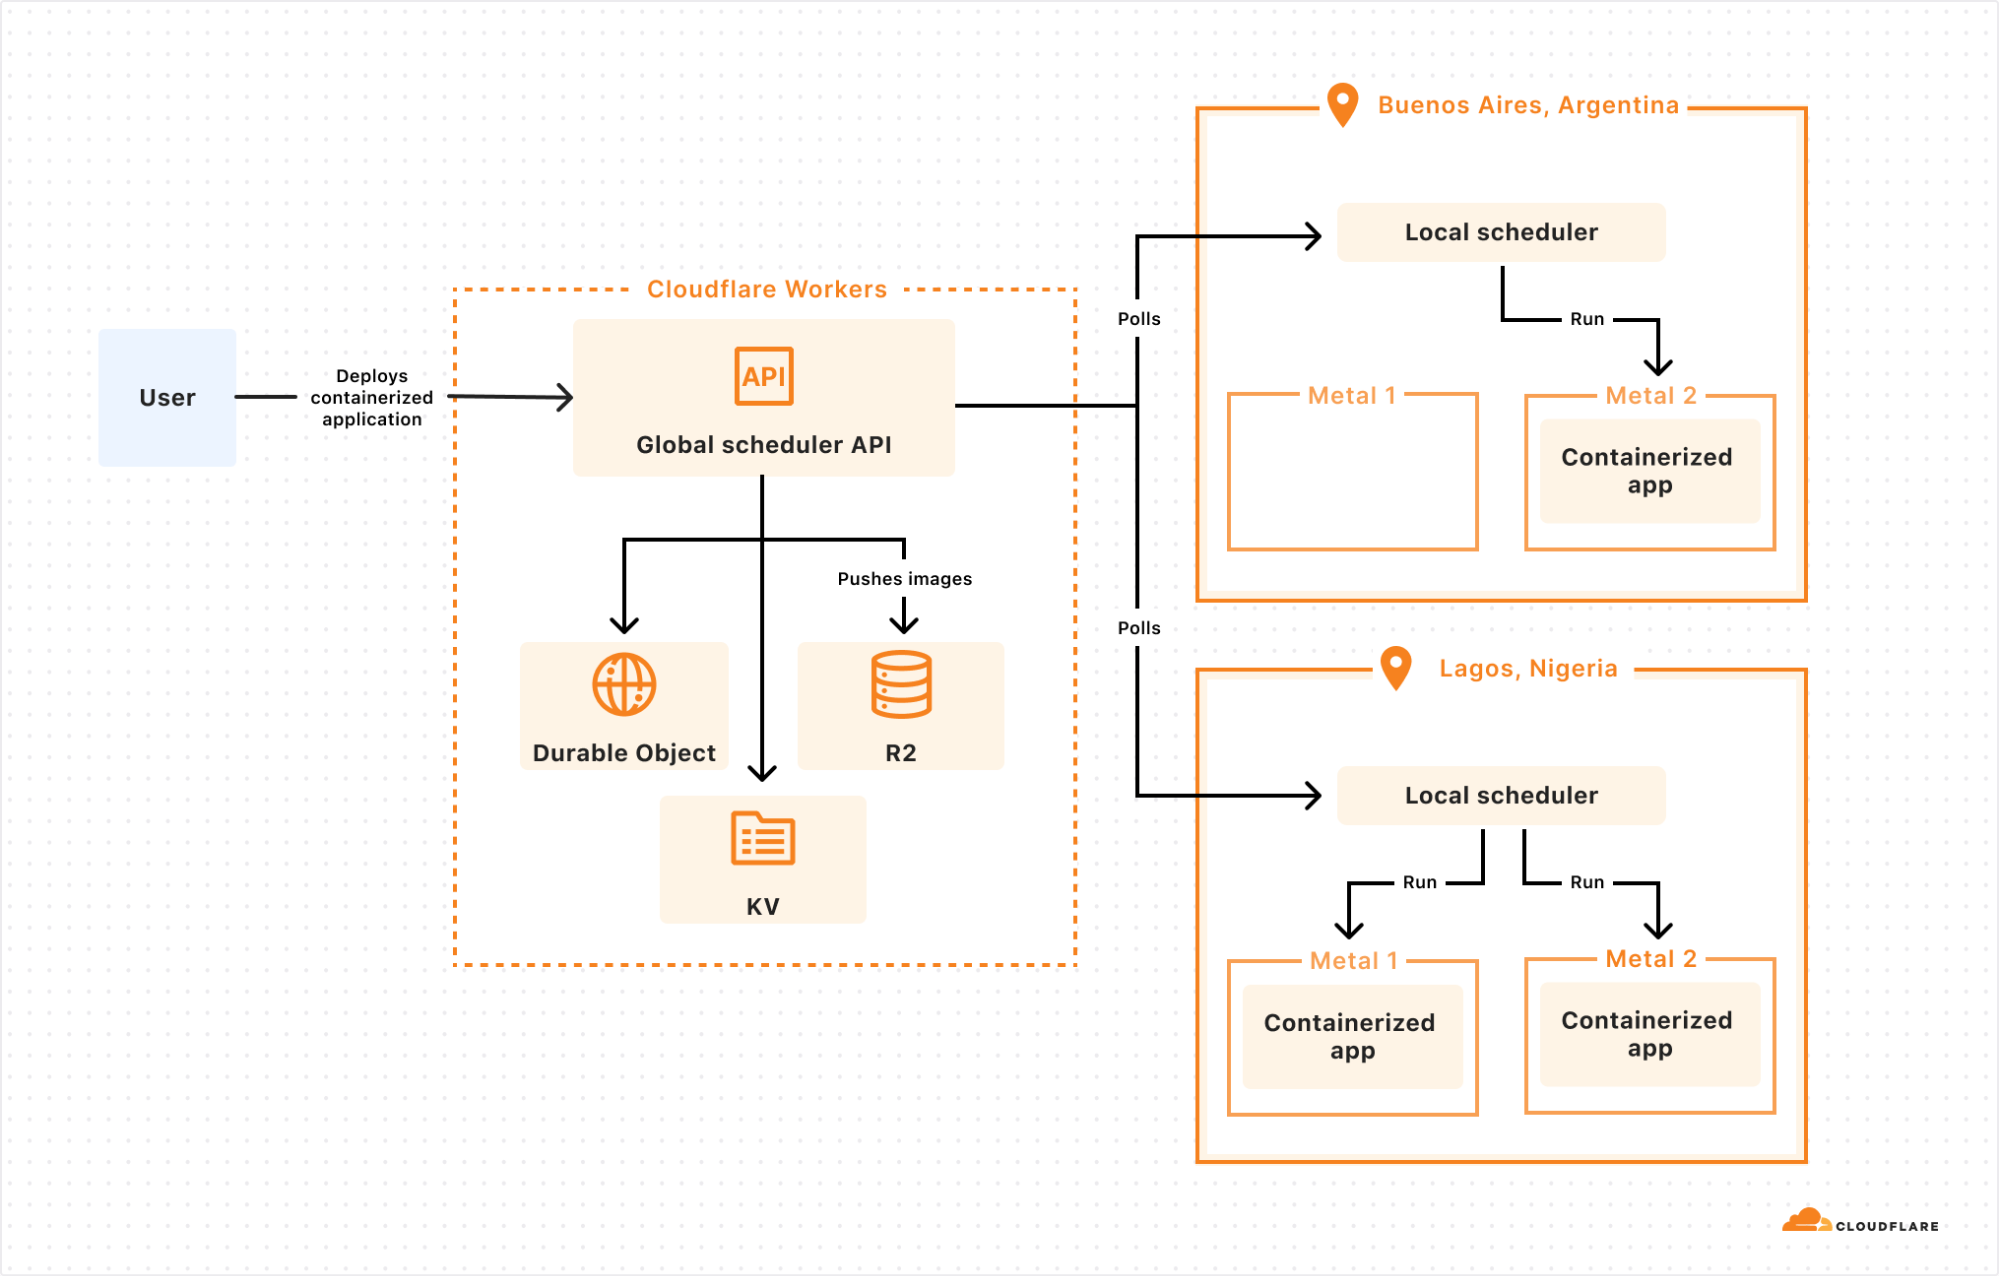

The global scheduler is built on Cloudflare Workers, Durable Objects, and KV, and decides which Cloudflare location to schedule the container to run in. Each location then runs its own scheduler, which decides which metals within that location to schedule the container to run on. Location schedulers monitor compute capacity, and expose this to the global scheduler. This allows Cloudflare to dynamically place workloads based on capacity and hardware availability (e.g. multiple types of GPUs) across our network.

Why does global scheduling matter?

When you run compute on a first generation cloud, the “contract” between the developer and the platform is that the developer must specify what runs where. This is regional scheduling, the status quo.

Let’s imagine for a second if we applied regional scheduling to running compute on Cloudflare’s network, with locations in 330+ cities, across 120+ countries. One of the obvious reasons people tell us they want to run on Cloudflare is because we have compute in places where others don’t, within 50ms of 95% of the world’s Internet-connected population. In South America, other clouds have one region in one city. Cloudflare has 19:
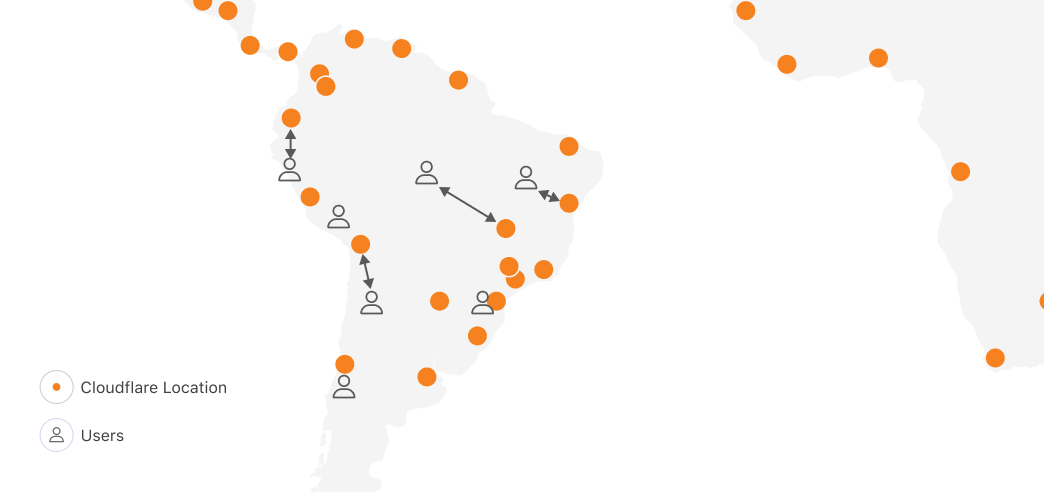

Running anywhere means you can be faster, highly available, and have more control over data location. But with regional scheduling, the more locations you run in, the more work you have to do. You configure and manage load balancing, routing, auto-scaling policies and more. Balancing performance and cost in a multi-region setup is literally a full-time job (or more) at most companies who have reached meaningful scale on traditional clouds.

But most importantly, no matter what tools you bring, you were the one who told the cloud provider, “run this container over here”. The cloud platform can’t move it for you, even if moving it would make your workload faster. This prevents the platform from adding locations, because for each location, it has to convince developers to take action themselves to move their compute workloads to the new location. Each new location carries a risk that developers won’t migrate workloads to it, or migrate too slowly, delaying the return on investment.

Global scheduling means Cloudflare can add capacity and use it immediately, letting you benefit from it. The “contract” between us and our customers isn’t tied to a specific datacenter or region, so we have permission to move workloads around to benefit customers. This flexibility plays an essential role in all of our own uses of our container platform, starting with GPUs and AI.

GPUs everywhere: Scheduling large images with Workers AI

In late 2023, we launched Workers AI, which provides fast, easy to use, and affordable GPU-backed AI inference.

The more efficiently we can use our capacity, the better pricing we can offer. And the faster we can make changes to which models run in which Cloudflare locations, the closer we can move AI inference to the application, lowering Time to First Token (TTFT). This also allows us to be more resilient to spikes in inference requests.

AI models that rely on GPUs present three challenges though:

  1. Models have different GPU memory needs. GPU memory is the most scarce resource, and different GPUs have different amounts of memory.

  2. Not all container runtimes, such as Firecracker, support GPU drivers and other dependencies.

  3. AI models, particularly LLMs, are very large. Even a smaller parameter model, like @cf/meta/llama-3.1-8b-instruct, is at least 5 GB. The larger the model, the more bytes we need to pull across the network when scheduling a model to run in a new location.

Let’s dive into how we solved each of these…

First, GPU memory needs. The global scheduler knows which Cloudflare locations have blocks of GPU memory available, and then delegates scheduling the workload on a specific metal to the local scheduler. This allows us to prioritize placement of AI models that use a large amount of GPU memory, and then move smaller models to other machines in the same location. By doing this, we maximize the overall number of locations that we run AI models in, and maximize our efficiency.

Second, container runtimes and GPU support. Thankfully, from day one we built our container platform to be runtime agnostic. Using a runtime agnostic scheduler, we’re able to support gVisor, Firecracker microVMs, and traditional VMs with QEMU. We are also evaluating adding support for another one: cloud-hypervisor which is based on rust-vmm and has a few compelling advantages for our use case:

  1. GPU passthrough support using VFIO

  2. vhost-user-net support, enabling high throughput between the host network interface and the VM

  3. vhost-user-blk support, adding flexibility to introduce novel network-based storage backed by other Cloudflare Workers products

  4. all the while being a smaller codebase than QEMU and written in a memory-safe language

Our goal isn’t to build a platform that makes you as the developer choose between runtimes, and ask, “should I use Firecracker or gVisor”. We needed this flexibility in order to be able to run workloads with different needs efficiently, including workloads that depend on GPUs. gVisor has GPU support, while Firecracker microVMs currently does not.

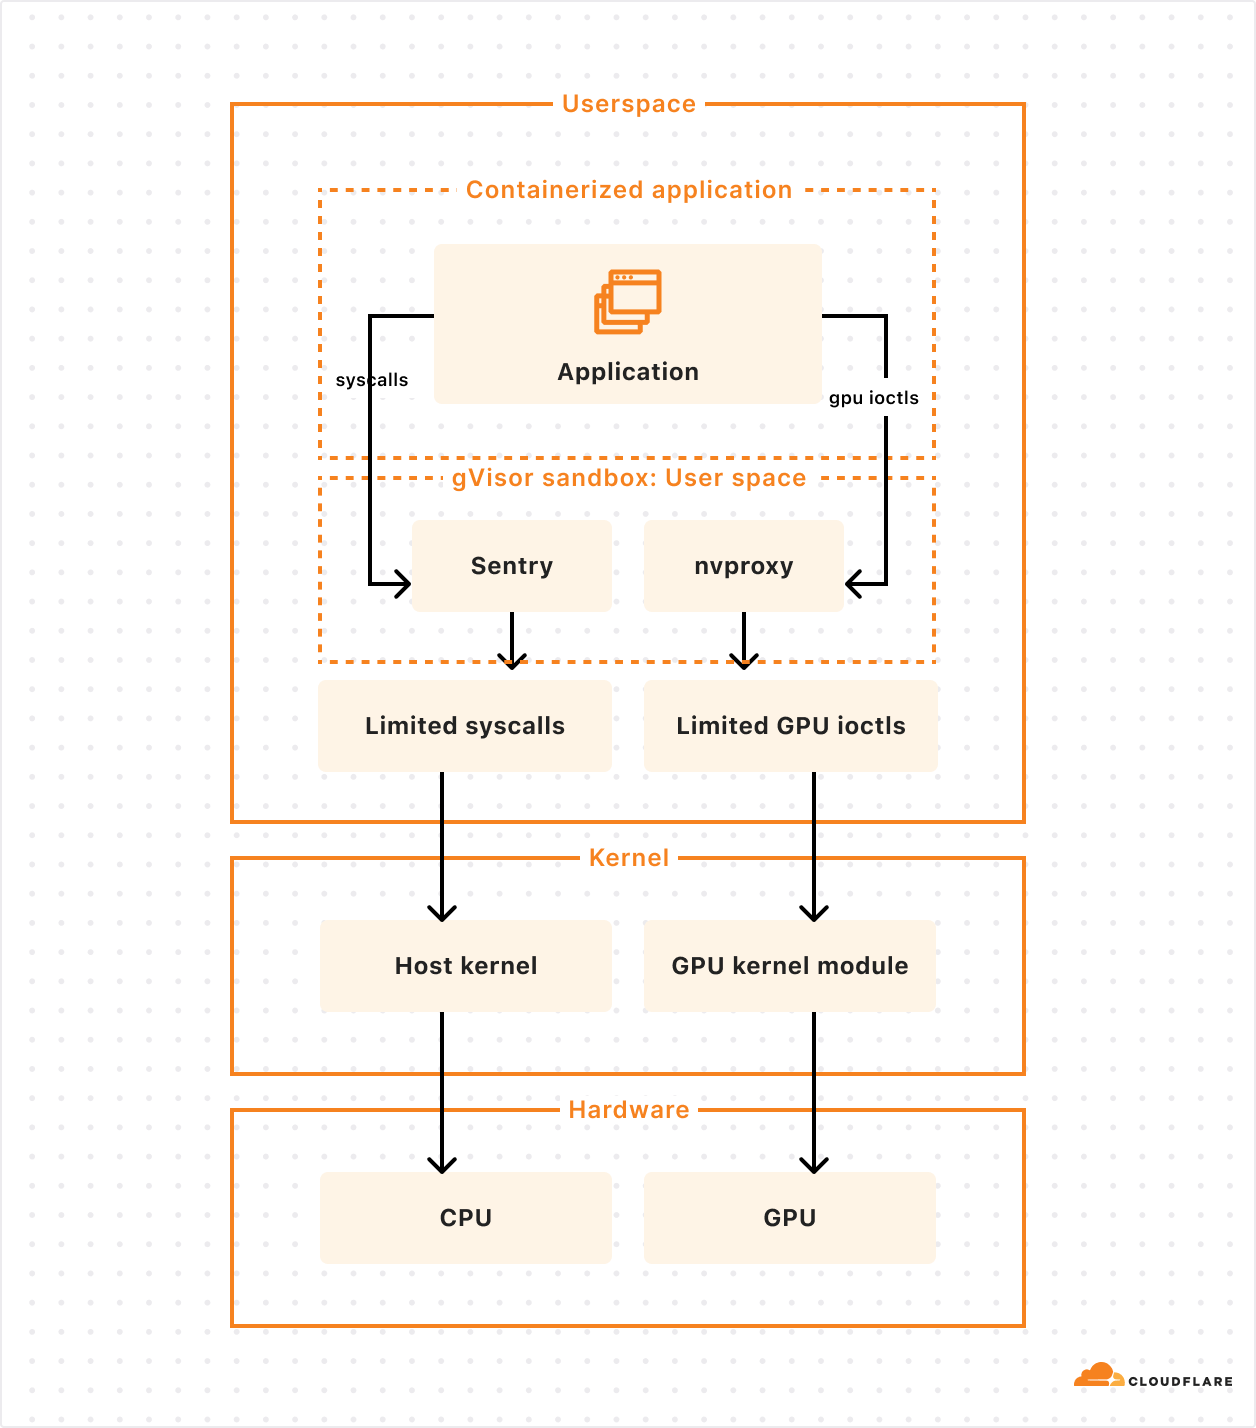
gVisor’s main component is an application kernel (called Sentry) that implements a Linux-like interface but is written in a memory-safe language (Go) and runs in userspace. It works by intercepting application system calls and acting as the guest kernel, without the need for translation through virtualized hardware.

The resource footprint of a containerized application running on gVisor is lower than a VM because it does not require managing virtualized hardware and booting up a kernel instance. However, this comes at the price of reduced application compatibility and higher per-system call overhead.

To add GPU support, the Google team introduced nvproxy which works using the same principles as described above for syscalls: it intercepts ioctls destined to the GPU and proxies a subset to the GPU kernel module.

To solve the third challenge, and make scheduling fast with large models, we weren’t satisfied with the status quo. So we did something about it.

Docker pull was too slow, so we fixed it (and cut the time in half)

Many of the images we need to run for AI inference are over 15 GB. Specialized inference libraries and GPU drivers add up fast. For example, when we make a scheduling decision to run a fresh container in Tokyo, naively running docker pull to fetch the image from a storage bucket in Los Angeles would be unacceptably slow. And scheduling speed is critical to being able to scale up and down in new locations in response to changes in traffic.

We had 3 essential requirements:

  • Pulling and pushing very large images should be fast

  • We should not rely on a single point of failure

  • Our teams shouldn’t waste time managing image registries

We needed globally distributed storage, so we used R2. We needed the highest cache hit rate possible, so we used Cloudflare’s Cache, and will soon use Tiered Cache. And we needed a fast container image registry that we could run everywhere, in every Cloudflare location, so we built and open-sourced serverless-registry, which is built on Workers. You can deploy serverless-registry to your own Cloudflare account in about 5 minutes. We rely on it in production.

This is fast, but we can be faster. Our performance bottleneck was, somewhat surprisingly, docker push. Docker uses gzip to compress and decompress layers of images while pushing and pulling. So we started using Zstandard (zstd) instead, which compresses and decompresses faster, and results in smaller compressed files.

In order to build, chunk, and push these images to the R2 registry, we built a custom CLI tool that we use internally in lieu of running docker build and docker push. This makes it easy to use zstd and split layers into 500 MB chunks, which allows uploads to be processed by Workers while staying under body size limits.

Using our custom build and push tool doubled the speed of image pulls. Our 30 GB GPU images now pull in 4 minutes instead of 8. We plan on open sourcing this tool in the near future.

Anycast is the gift that keeps on simplifying — Virtual IPs and the Global State Router

We still had another challenge to solve. And yes, we solved it with anycast. We’re Cloudflare, did you expect anything else?

First, a refresher — Cloudflare operates Unimog, a Layer 4 load balancer that handles all incoming Cloudflare traffic. Cloudflare’s network uses anycast, which allows a single IP address to route requests to a variety of different locations. For most Cloudflare services with anycast, the given IP address will route to the nearest Cloudflare data center, reducing latency. Since Cloudflare runs almost every service in every data center, Unimog can simply route traffic to any Cloudflare metal that is online and has capacity, without needing to map traffic to a specific service that runs on specific metals, only in some locations.

The new compute-heavy, GPU-backed workloads we were taking on forced us to confront this fundamental “everything runs everywhere” assumption. If we run a containerized workflow in 20 Cloudflare locations, how does Unimog know which locations, and which metals, it runs in? You might say “just bring your own load balancer” — but then what happens when you make scheduling decisions to migrate a workload between locations, scale up, or scale down?

Anycast is foundational to how we build fast and simple products on our network, and we needed a way to keep building new types of products this way — where a team can deploy an application, get back a single IP address, and rely on the platform to balance traffic, taking load, container health, and latency into account, without extra configuration. We started letting teams use the container platform without solving this, and it was painfully clear that we needed to do something about it.

So we started integrating directly into our networking stack, building a sidecar service to Unimog. We’ll call this the Global State Router. Here’s how it works:

  • An eyeball makes a request to a virtual IP address issued by Cloudflare

  • Request sent to the best location as determined by BGP routing. This is anycast routing.

  • A small eBPF program sits on the main networking interface and ensures packets bound to a virtual IP address are handled by the Global State Router.

  • The main Global State Router program contains a mapping of all anycast IPs addresses to potential end destination container IP addresses. It updates this mapping based on container health, readiness, distance, and latency. Using this information, it picks a best-fit container.

  • Packets are forwarded at the L4 layer.

  • When a target container’s server receives a packet, its own Global State Router program intercepts the packet and routes it to the local container.
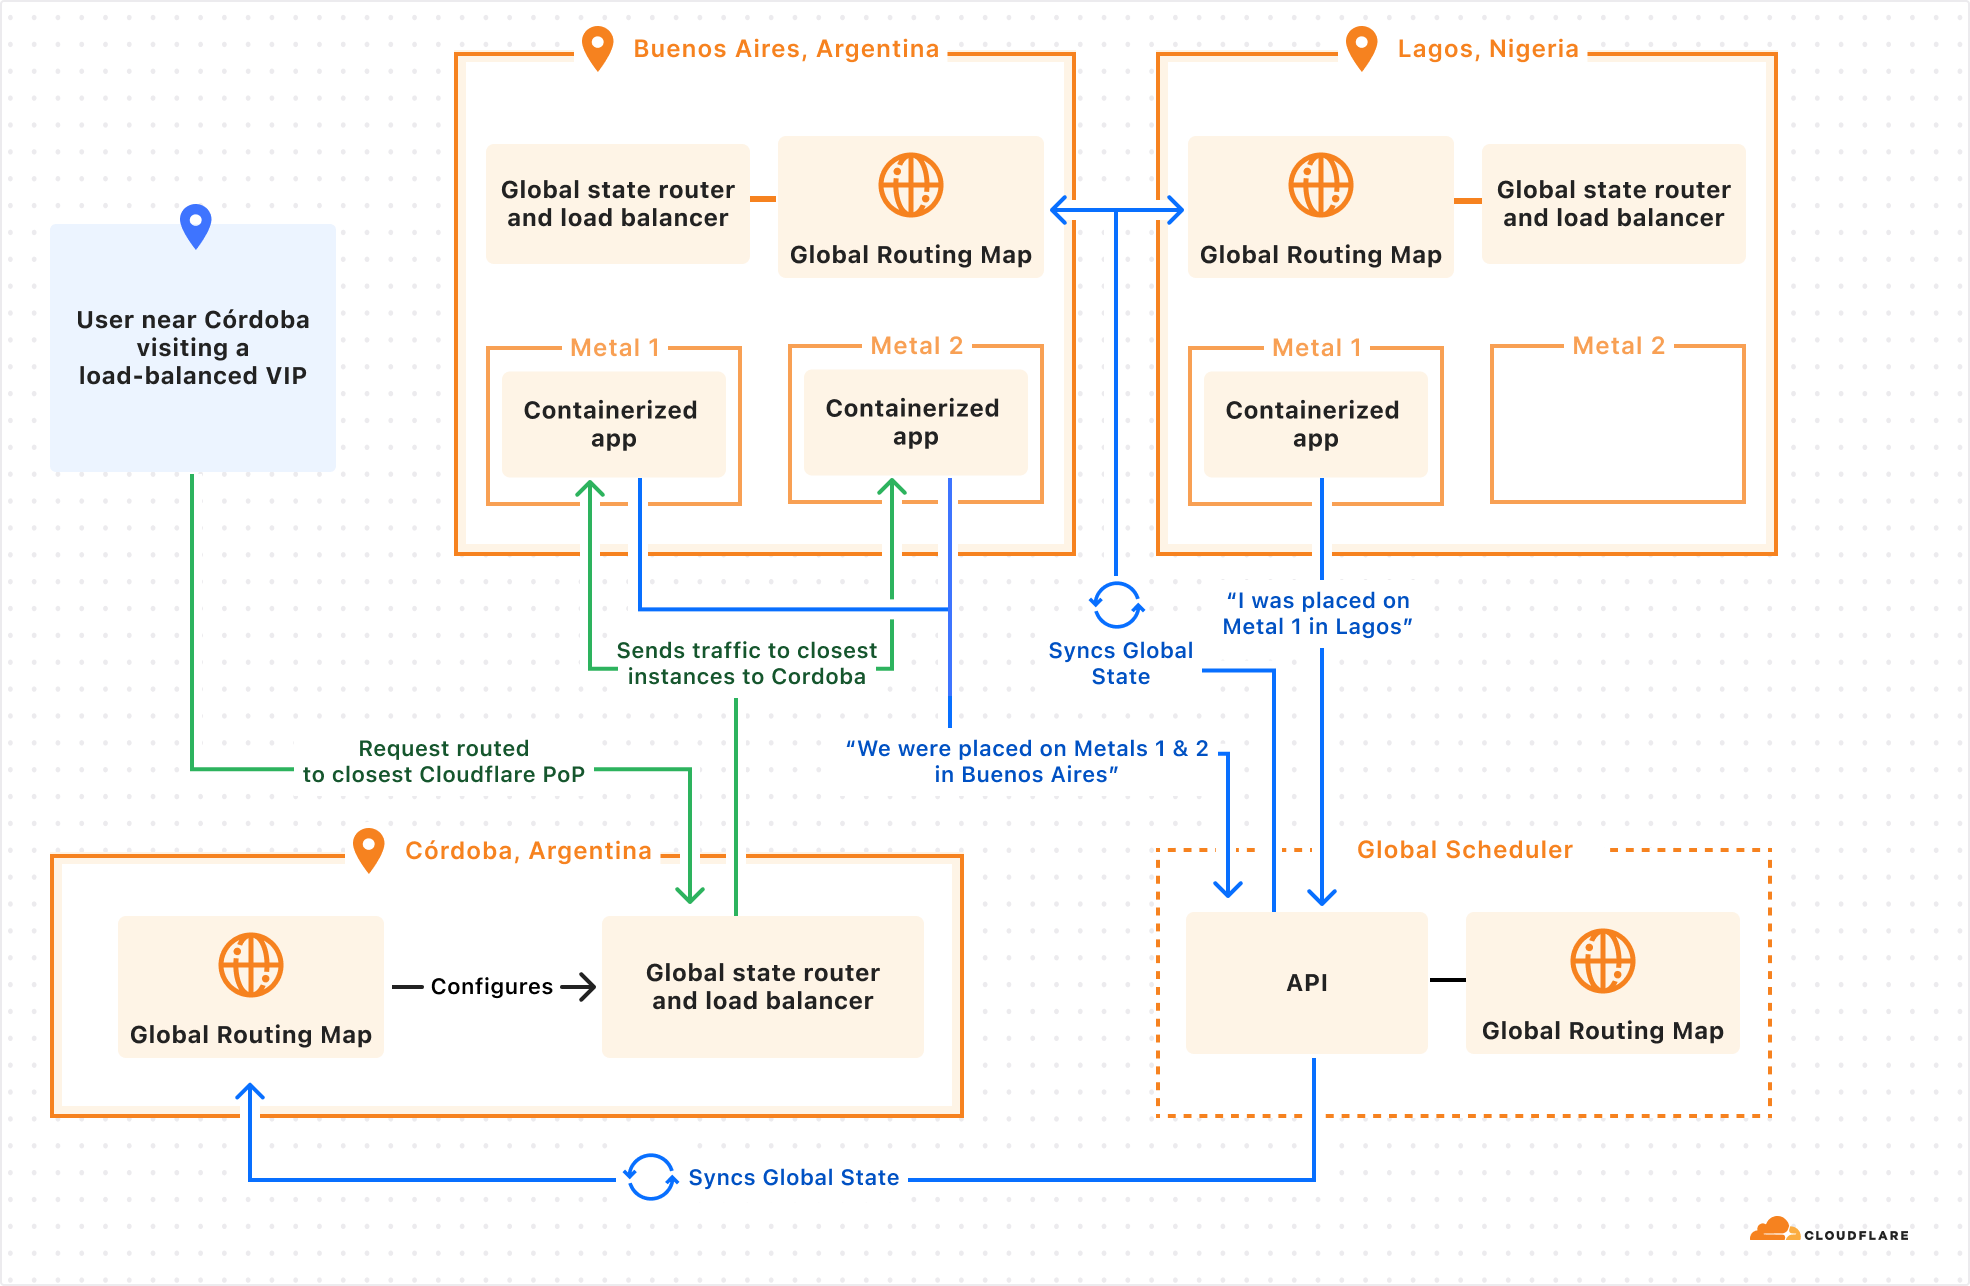

This might sound like just a lower level networking detail, disconnected from developer experience. But by integrating directly with Unimog, we can let developers:

  1. Push a containerized application to Cloudflare.

  2. Provide constraints, health checks, and load metrics that describe what the application needs.

  3. Delegate scheduling and scaling many containers across Cloudflare’s network.

  4. Get back a single IP address that can be used everywhere.

We’re actively working on this, and are excited to continue building on Cloudflare’s anycast capabilities, and pushing to keep the simplicity of running “everywhere” with new categories of workloads.

Low latency & global — Remote Browser Isolation & Browser Rendering

Our container platform actually started because of a very specific challenge, running Remote Browser Isolation across our network. Remote Browser Isolation provides Chromium browsers that run on Cloudflare, in containers, rather than on the end user’s own computer. Only the rendered output is sent to the end user. This provides a layer of protection against zero-day browser vulnerabilities, phishing attacks, and ransomware.

Location is critical — people expect their interactions with a remote browser to feel just as fast as if it ran locally. If the server is thousands of miles away, the remote browser will feel slow. Running across Cloudflare’s network of over 330 locations means the browser is nearly always as close to you as possible.

Imagine a user in Santiago, Chile, if they were to access a browser running in the same city, each interaction would incur negligible additional latency. Whereas a browser in Buenos Aires might add 21 ms, São Paulo might add 48 ms, Bogota might add 67 ms, and Raleigh, NC might add 128 ms. Where the container runs significantly impacts the latency of every user interaction with the browser, and therefore the experience as a whole.

It’s not just browser isolation that benefits from running near the user: WebRTC servers stream video better, multiplayer games have less lag, online advertisements can be served faster, financial transactions can be processed faster. Our container platform lets us run anything we need to near the user, no matter where they are in the world.

Using spare compute — “off-peak” jobs for Workers CI/CD builds

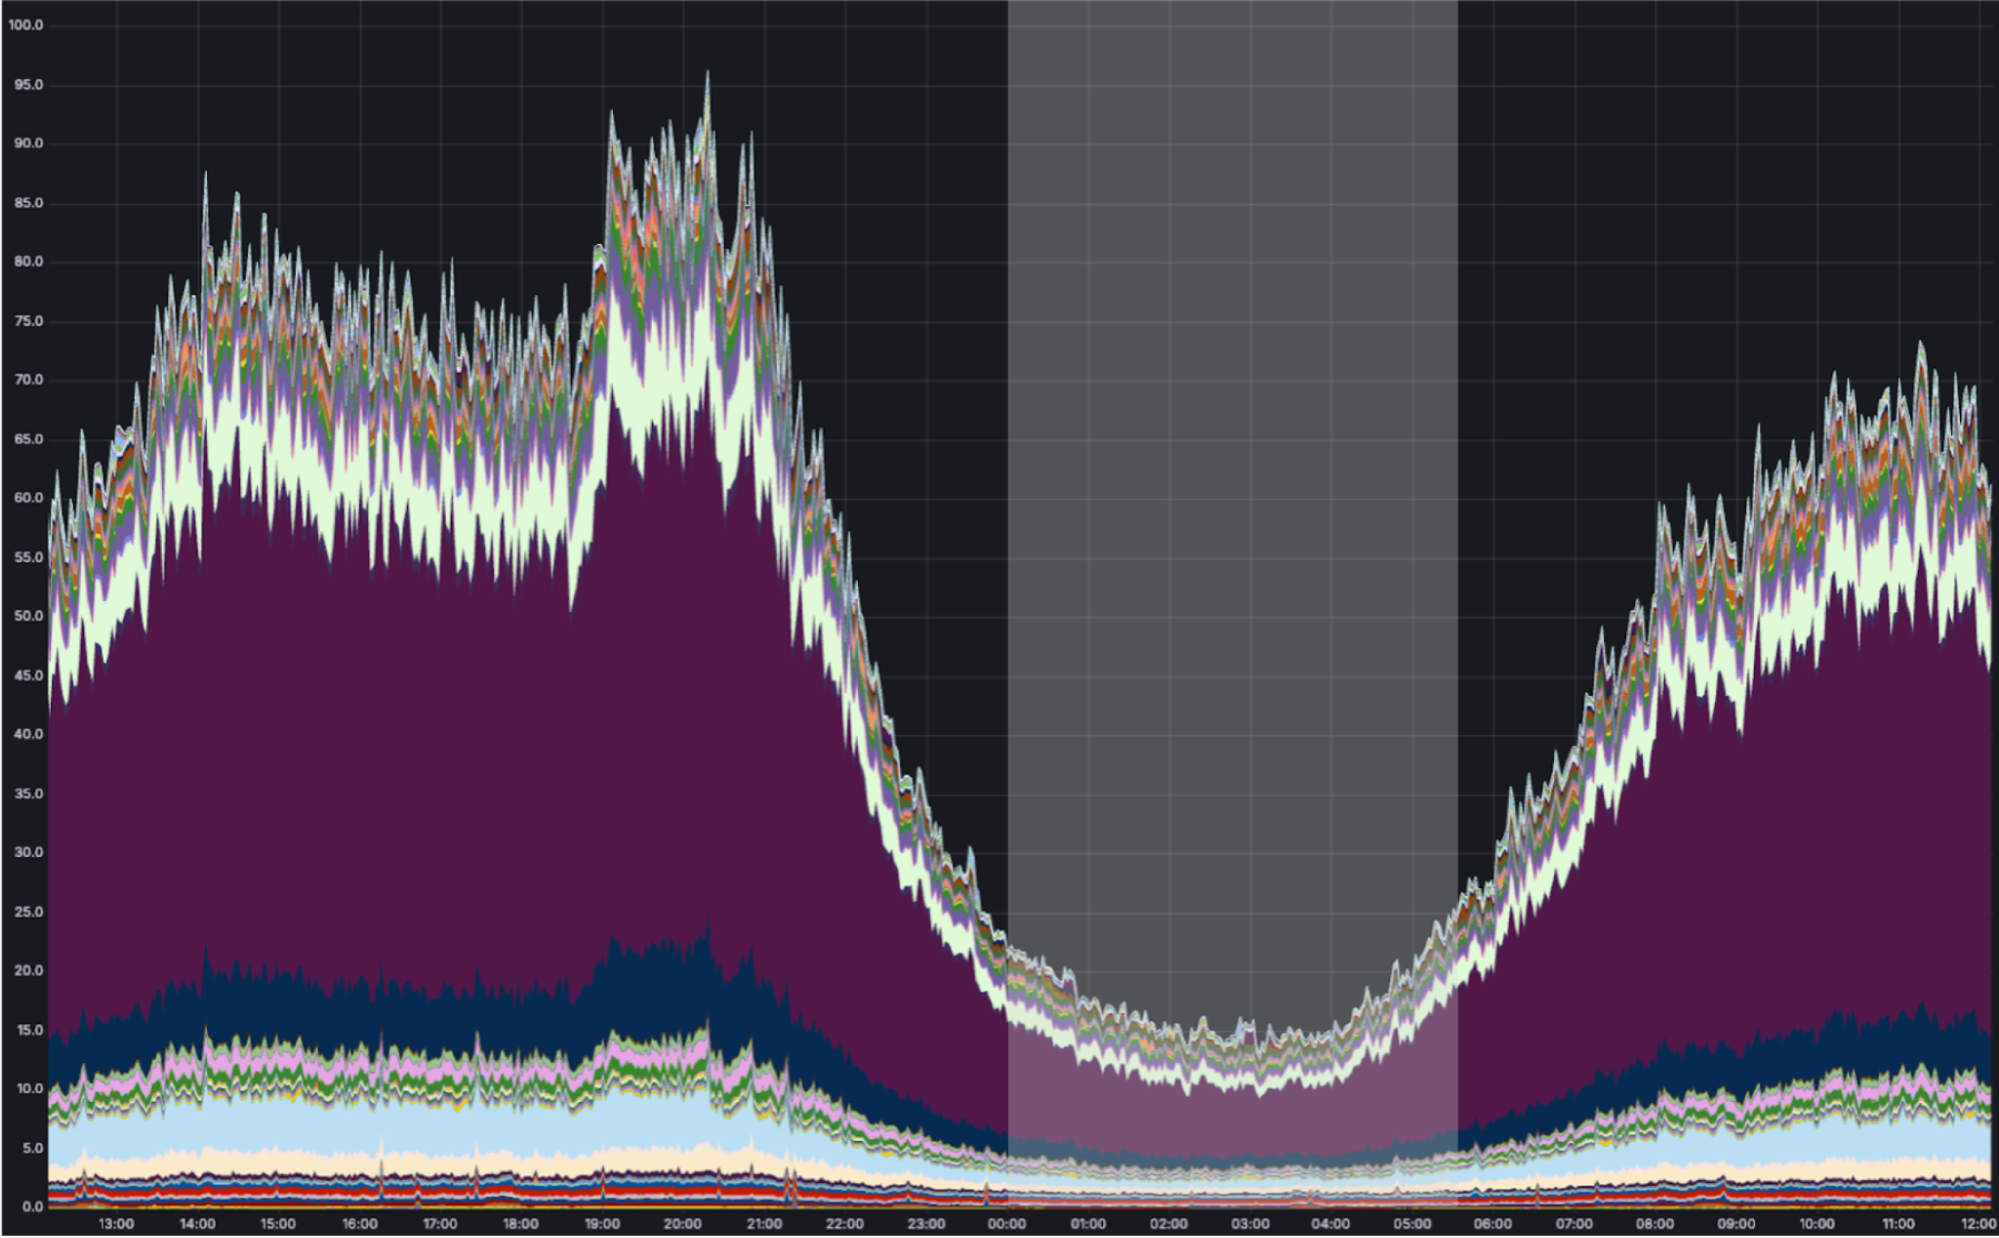
At any hour of the day, Cloudflare has many CPU cores that sit idle. This is compute power that could be used for something else.

Via anycast, most of Cloudflare’s traffic is handled as close as possible to the eyeball (person) that requested it. Most of our traffic originates from eyeballs. And the eyeballs of (most) people are closed and asleep between midnight and 5:00 AM local time. While we use our compute capacity very efficiently during the daytime in any part of the world, overnight we have spare cycles. Consider what a map of the world looks like at night-time in Europe and Africa:
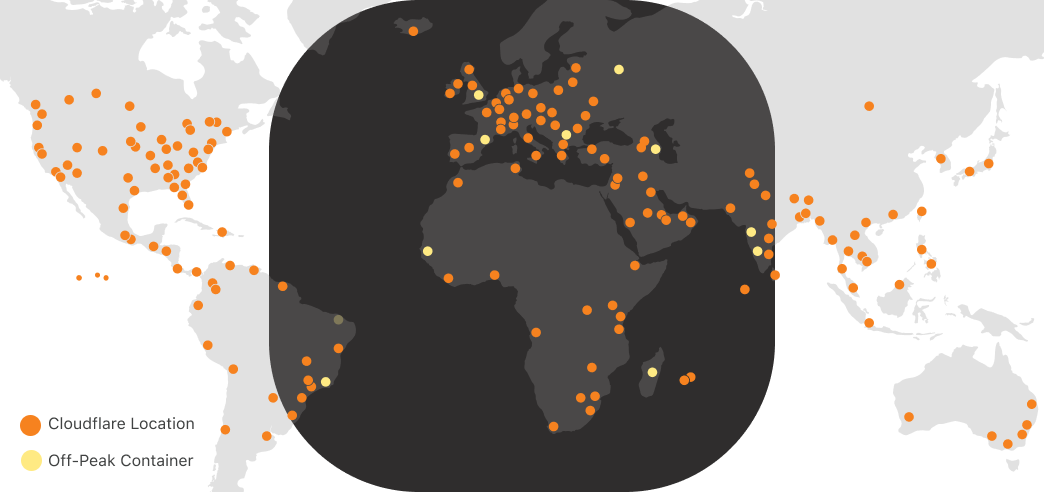

As shown above, we can run containers during “off-peak” in Cloudflare locations receiving low traffic at night. During this time, the CPU utilization of a typical Cloudflare metal looks something like this:

We have many “background” compute workloads at Cloudflare. These are workloads that don’t actually need to run close to the eyeball because there is no eyeball waiting on the request. The challenge is that many of these workloads require running untrusted code — either a dependency on open-source code that we don’t trust enough to run outside of a sandboxed environment, or untrusted code that customers deploy themselves. And unlike Cron Triggers, which already make a best-effort attempt to use off-peak compute, these other workloads can’t run in v8 isolates.

On Builder Day 2024, we announced Workers Builds in open beta. You connect your Worker to a git repository, and Cloudflare builds and deploys your Worker each time you merge a pull request. Workers Builds run on our containers platform, using otherwise idle “off-peak” compute, allowing us to offer lower pricing, and hold more capacity for unexpected spikes in traffic in Cloudflare locations during daytime hours when load is highest. We preserve our ability to serve requests as close to the eyeball as possible where it matters, while using the full compute capacity of our network.

We developed a purpose-built API for these types of jobs. The Workers Builds service has zero knowledge of where Cloudflare has spare compute capacity on its network — it simply schedules an “off-peak” job to run on the containers platform, by defining a scheduling policy:

scheduling_policy: "off-peak"

Making off-peak jobs faster with prewarmed images

Just because a workload isn’t “eyeball-facing” doesn’t mean speed isn’t relevant. When a build job starts, you still want it to start as soon as possible.

Each new build requires a fresh container though, and we must avoid reusing containers to provide strong isolation between customers. How can we keep build job start times low, while using a new container for each job without over-provisioning? 

We prewarm servers with the proper image. 

Before a server becomes eligible to receive an “off peak” job, the container platform instructs it to download the correct image. Once the image is downloaded and cached locally, new containers can start quickly in a Firecracker VM after receiving a request for a new build. When a build completes, we throw away the container, and start the next build using a fresh container based on the prewarmed image.

Without prewarming, pulling and unpacking our Workers Build images would take roughly 75 seconds. With prewarming, we’re able to spin up a new container in under 10 seconds. We expect this to get even faster as we introduce optimizations like pre-booting images before new runs, or Firecracker snapshotting, which can restore a VM in under 200ms.

Workers and containers, better together

As more of our own engineering teams rely on our containers platform in production, we’ve noticed a pattern: they want a deeper integration with Workers.

We plan to give it to them. 

Let’s take a look at a project deployed on our container platform already, Key Transparency. If the container platform were highly integrated with Workers, what would this team’s experience look like?

Cloudflare regularly audits changes to public keys used by WhatsApp for encrypting messages between users. Much of the architecture is built on Workers, but there are long-running compute-intensive tasks that are better suited for containers.

We don’t want our teams to have to jump through hoops to deploy a container and integrate with Workers. They shouldn’t have to pick specific regions to run in, figure out scaling, expose IPs and handle IP updates, or set up Worker-to-container auth.

We’re still exploring many different ideas and API designs, and we want your feedback. But let’s imagine what it might look like to use Workers, Durable Objects and Containers together.

In this case, an outer layer of Workers handles most business logic and ingress, a specialized Durable Object is configured to run alongside our new container, and the platform ensures the image is loaded on the right metals and can scale to meet demand.
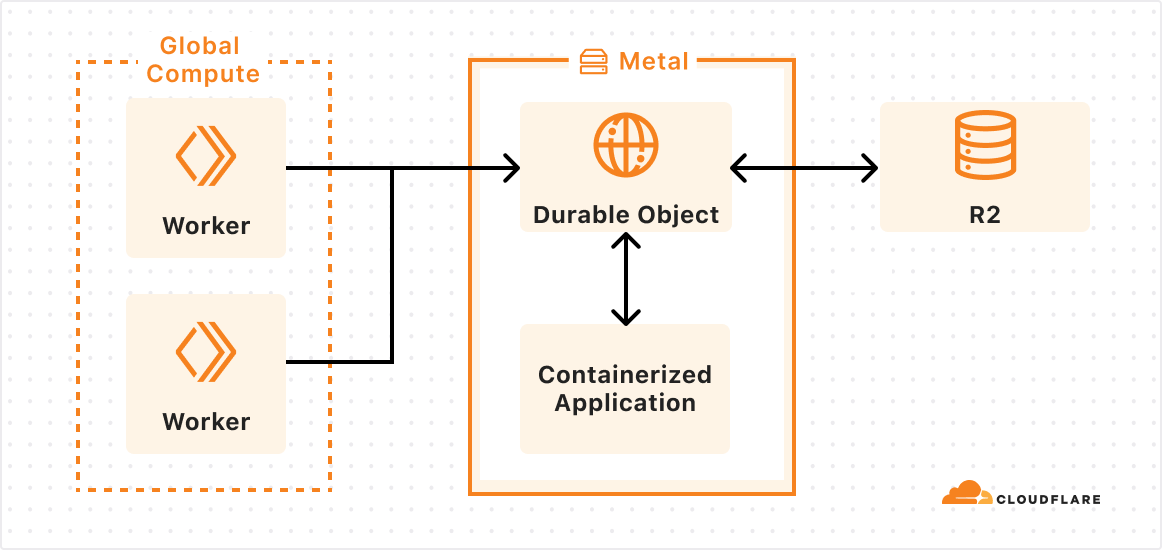

I add a containerized app to the wrangler.toml configuration file of my Worker (or Terraform):

[[container-app]]
image = "./key-transparency/verifier/Dockerfile"
name = "verifier"

[durable_objects]
bindings = { name = "VERIFIER", class_name = "Verifier", container = "verifier" } }

Then, in my Worker, I call the runVerification RPC method of my Durable Object:

fetch(request, env, ctx) {
  const id = new URL(request.url).searchParams.get('id')
  const durableObjectId = env.VERIFIER.idFromName(request.params.id);
  await env.VERIFIER.get(durableObjectId).runVerification()
  //...
}

From my Durable Object I can boot, configure, mount storage buckets as directories, and make HTTP requests to the container:

class Verifier extends DurableObject {
  constructor(state, env) {
    this.ctx.blockConcurrency(async () => {

      // starts the container
      await this.ctx.container.start();

      // configures the container before accepting traffic
      const config = await this.state.storage.get("verifierConfig");
      await this.ctx.container.fetch("/set-config", { method: "PUT", body: config});
    })
  }

  async runVerification(updateId) {
    // downloads & mounts latest updates from R2
    const latestPublicKeyUpdates = await this.env.R2.get(`public-key-updates/${updateId}`);
    await this.ctx.container.mount(`/updates/${updateId}`, latestPublicKeyUpdates);

    // starts verification via HTTP call 
    return await this.ctx.container.fetch(`/verifier/${updateId}`);
  }
}

And… that’s it.

I didn’t have to worry about placement, scaling, service discovery authorization, and I was able to leverage integrations into other services like KV and R2 with just a few lines of code. The container platform took care of routing, placement, and auth. If I needed more instances, I could call the binding with a new ID, and the platform would scale up containers for me.

We are still in the early stages of building these integrations, but we’re excited about everything that containers will bring to Workers and vice versa.

So, what do you want to build?

If you’ve read this far, there’s a non-zero chance you were hoping to get to run a container yourself on our network. While we’re not ready (quite yet) to open up the platform to everyone, now that we’ve built a few GA products on our container platform, we’re looking for a handful of engineering teams to start building, in advance of wider availability in 2025. And we’re continuing to hire engineers to work on this.

We’ve told you about our use cases for containers, and now it’s your turn. If you’re interested, tell us here what you want to build, and why it goes beyond what’s possible today in Workers and on our Developer Platform. What do you wish you could build on Cloudflare, but can’t yet today?
Zero-latency SQLite storage in every Durable Object

Post Syndicated from Kenton Varda original https://blog.cloudflare.com/sqlite-in-durable-objects

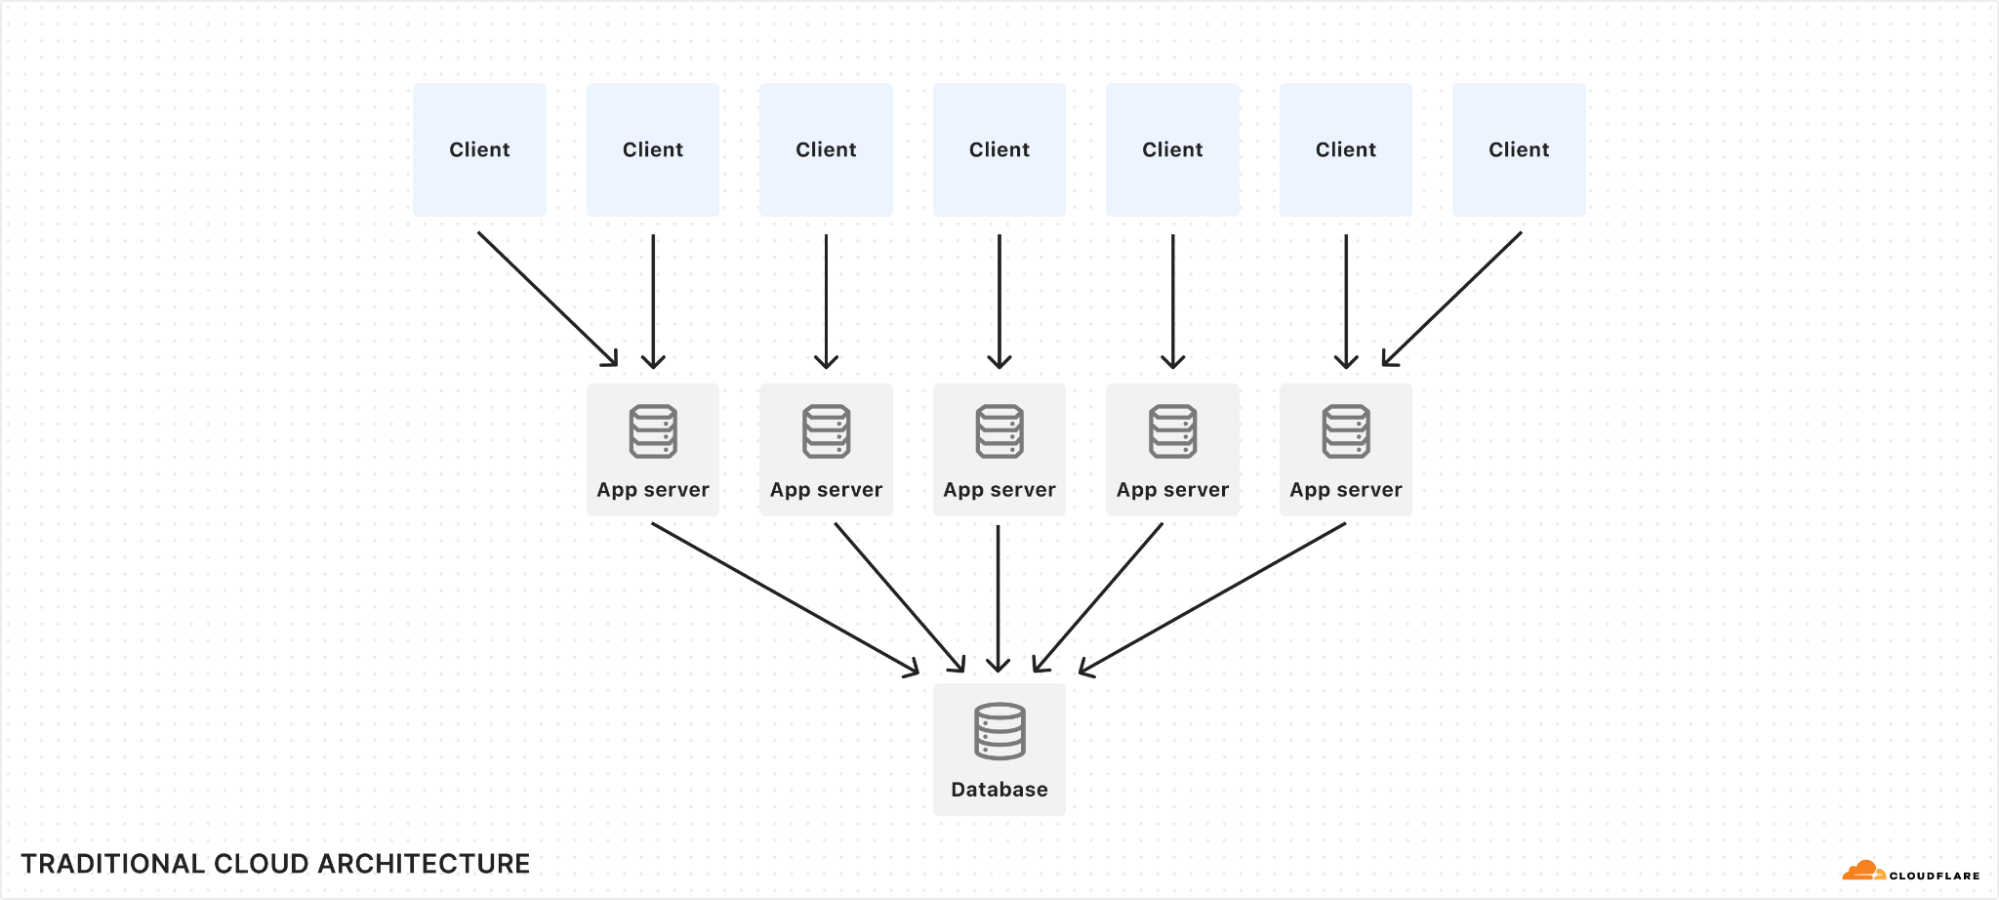
Traditional cloud storage is inherently slow, because it is normally accessed over a network and must carefully synchronize across many clients that could be accessing the same data. But what if we could instead put your application code deep into the storage layer, such that your code runs directly on the machine where the data is stored, and the database itself executes as a local library embedded inside your application?

Durable Objects (DO) are a novel approach to cloud computing which accomplishes just that: Your application code runs exactly where the data is stored. Not just on the same machine: your storage lives in the same thread as the application, requiring not even a context switch to access. With proper use of caching, storage latency is essentially zero, while nevertheless being durable and consistent.

Until today, DOs only offered key/value oriented storage. But now, they support a full SQL query interface with tables and indexes, through the power of SQLite.

SQLite is the most-used SQL database implementation in the world, with billions of installations. It’s on practically every phone and desktop computer, and many embedded devices use it as well. It’s known to be blazingly fast and rock solid. But it’s been less common on the server. This is because traditional cloud architecture favors large distributed databases that live separately from application servers, while SQLite is designed to run as an embedded library. In this post, we’ll show you how Durable Objects turn this architecture on its head and unlock the full power of SQLite in the cloud.


Refresher: what are Durable Objects?

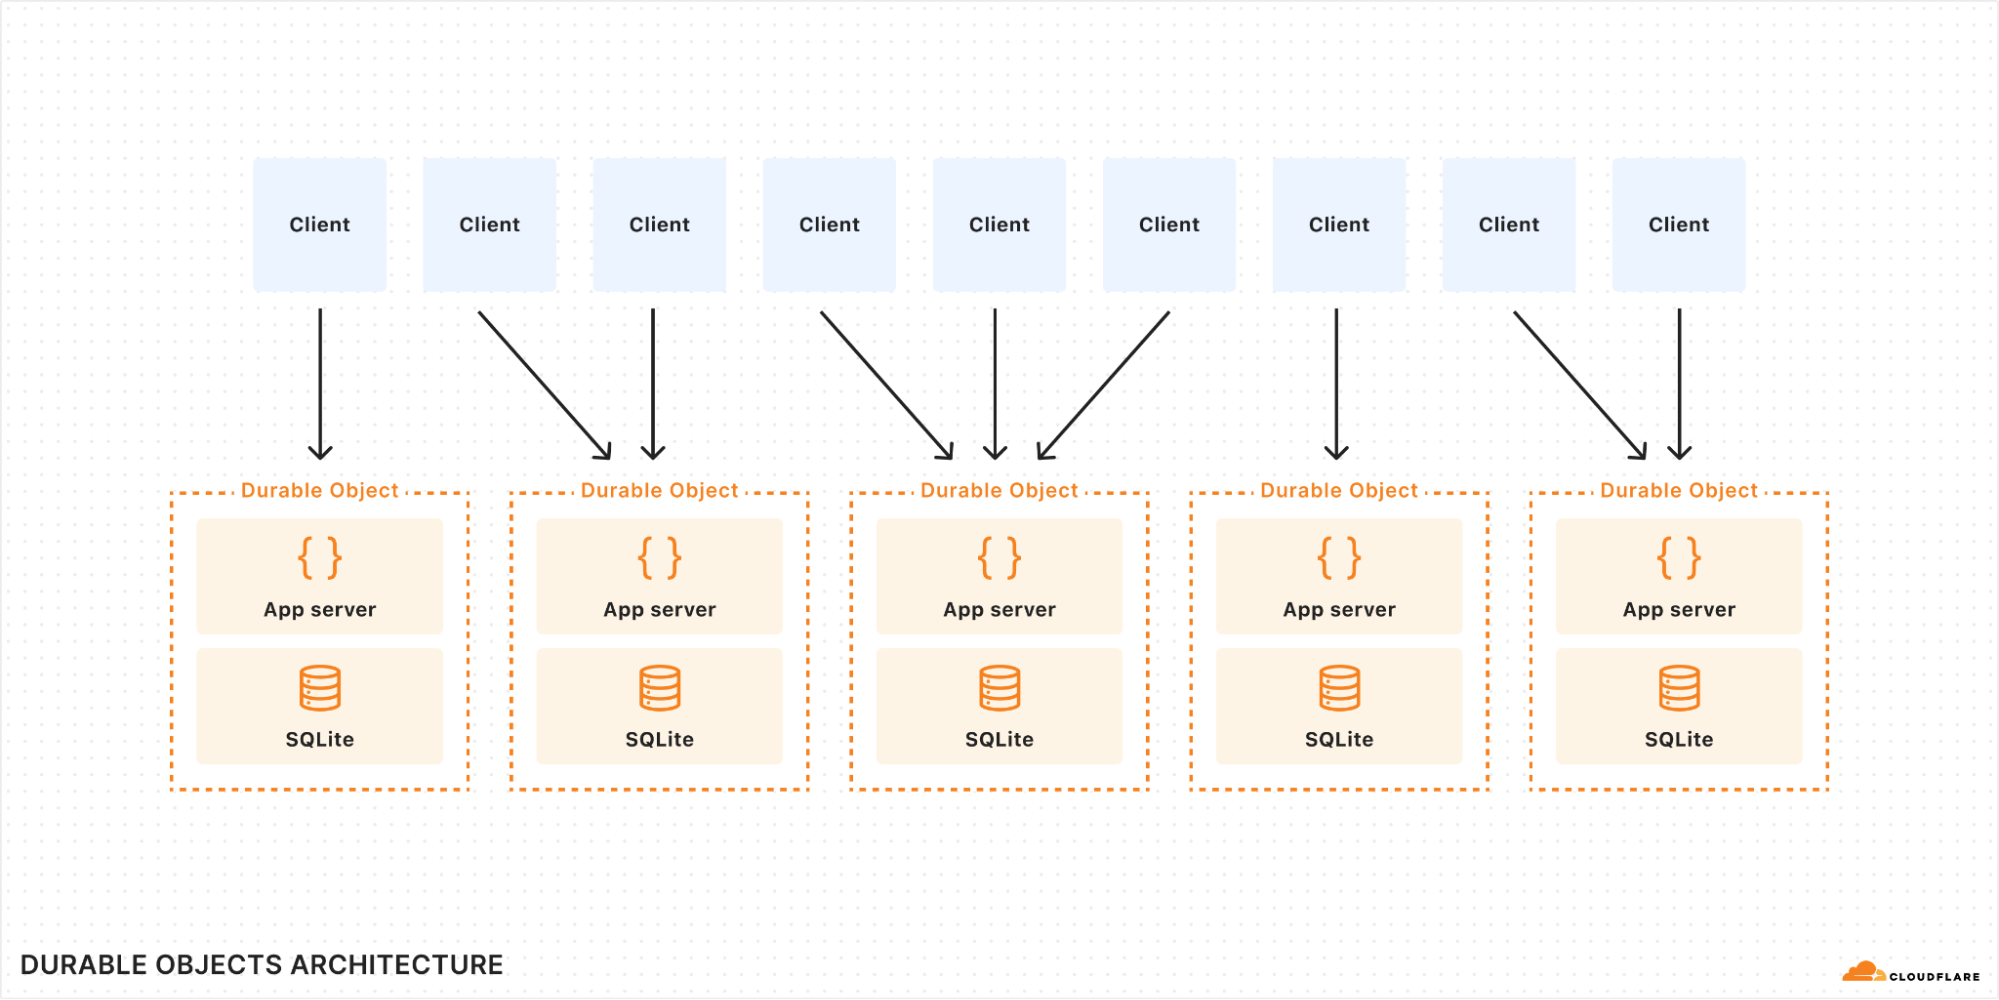
Durable Objects (DOs) are a part of the Cloudflare Workers serverless platform. A DO is essentially a small server that can be addressed by a unique name and can keep state both in-memory and on-disk. Workers running anywhere on Cloudflare’s network can send messages to a DO by its name, and all messages addressed to the same name — from anywhere in the world — will find their way to the same DO instance.

DOs are intended to be small and numerous. A single application can create billions of DOs distributed across our global network. Cloudflare automatically decides where a DO should live based on where it is accessed, automatically starts it up as needed when requests arrive, and shuts it down when idle. A DO has in-memory state while running and can also optionally store long-lived durable state. Since there is exactly one DO for each name, a DO can be used to coordinate between operations on the same logical object.

For example, imagine a real-time collaborative document editor application. Many users may be editing the same document at the same time. Each user’s changes must be broadcast to other users in real time, and conflicts must be resolved. An application built on DOs would typically create one DO for each document. The DO would receive edits from users, resolve conflicts, broadcast the changes back out to other users, and keep the document content updated in its local storage.

DOs are especially good at real-time collaboration, but are by no means limited to this use case. They are general-purpose servers that can implement any logic you desire to serve requests. Even more generally, DOs are a basic building block for distributed systems.

When using Durable Objects, it’s important to remember that they are intended to scale out, not up. A single object is inherently limited in throughput since it runs on a single thread of a single machine. To handle more traffic, you create more objects. This is easiest when different objects can handle different logical units of state (like different documents, different users, or different “shards” of a database), where each unit of state has low enough traffic to be handled by a single object. But sometimes, a lot of traffic needs to modify the same state: consider a vote counter with a million users all trying to cast votes at once. To handle such cases with Durable Objects, you would need to create a set of objects that each handle a subset of traffic and then replicate state to each other. Perhaps they use CRDTs in a gossip network, or perhaps they implement a fan-in/fan-out approach to a single primary object. Whatever approach you take, Durable Objects make it fast and easy to create more stateful nodes as needed.

Why is SQLite-in-DO so fast?

In traditional cloud architecture, stateless application servers run business logic and communicate over the network to a database. Even if the network is local, database requests still incur latency, typically measured in milliseconds.

When a Durable Object uses SQLite, SQLite is invoked as a library. This means the database code runs not just on the same machine as the DO, not just in the same process, but in the very same thread. Latency is effectively zero, because there is no communication barrier between the application and SQLite. A query can complete in microseconds.

Reads and writes are synchronous

The SQL query API in DOs does not require you to await results — they are returned synchronously:

// No awaits!
let cursor = sql.exec("SELECT name, email FROM users");
for (let user of cursor) {
  console.log(user.name, user.email);
}

This may come as a surprise to some. Querying a database is I/O, right? I/O should always be asynchronous, right? Isn’t this a violation of the natural order of JavaScript?

It’s OK! The database content is probably cached in memory already, and SQLite is being called as a library in the same thread as the application, so the query often actually won’t spend any time at all waiting for I/O. Even if it does have to go to disk, it’s a local SSD. You might as well consider the local disk as just another layer in the memory cache hierarchy: L5 cache, if you will. In any case, it will respond quickly.

Meanwhile, synchronous queries provide some big benefits. First, the logistics of asynchronous event loops have a cost, so in the common case where the data is already in memory, a synchronous query will actually complete faster than an async one.

More importantly, though, synchronous queries help you avoid subtle bugs. Any time your application awaits a promise, it’s possible that some other code executes while you wait. The state of the world may have changed by the time your await completes. Maybe even other SQL queries were executed. This can lead to subtle bugs that are hard to reproduce because they require events to happen at just the wrong time. With a synchronous API, though, none of that can happen. Your code always executes in the order you wrote it, uninterrupted.

Fast writes with Output Gates

Database experts might have a deeper objection to synchronous queries: Yes, caching may mean we can perform reads and writes very fast. However, in the case of a write, just writing to cache isn’t good enough. Before we return success to our client, we must confirm that the write is actually durable, that is, it has actually made it onto disk or network storage such that it cannot be lost if the power suddenly goes out.

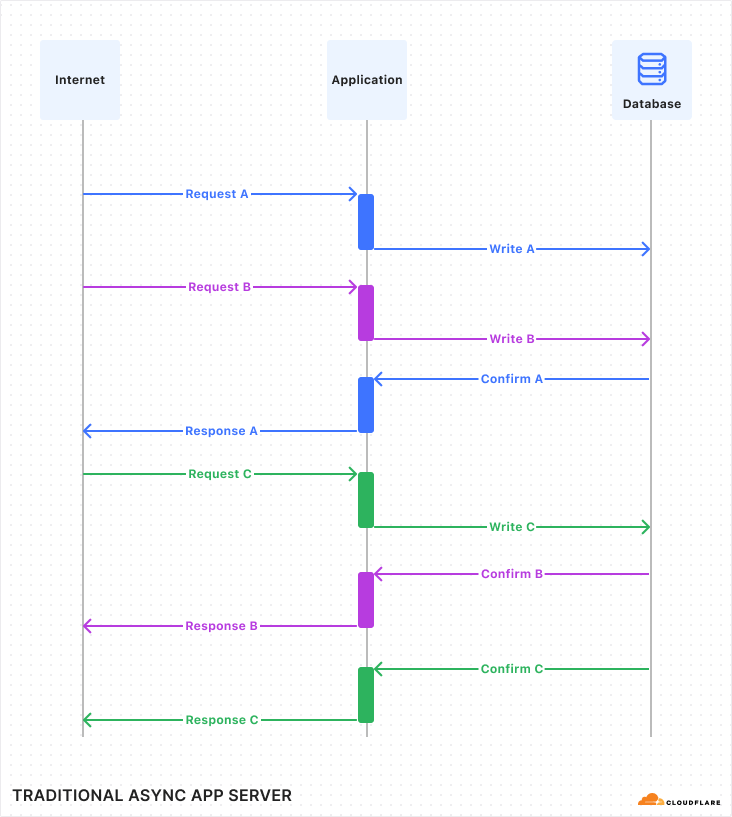
Normally, a database would confirm all writes before returning to the application. So if the query is successful, it is confirmed. But confirming writes can be slow, because it requires waiting for the underlying storage medium to respond. Normally, this is OK because the write is performed asynchronously, so the program can go on and work on other things while it waits for the write to finish. It looks kind of like this:


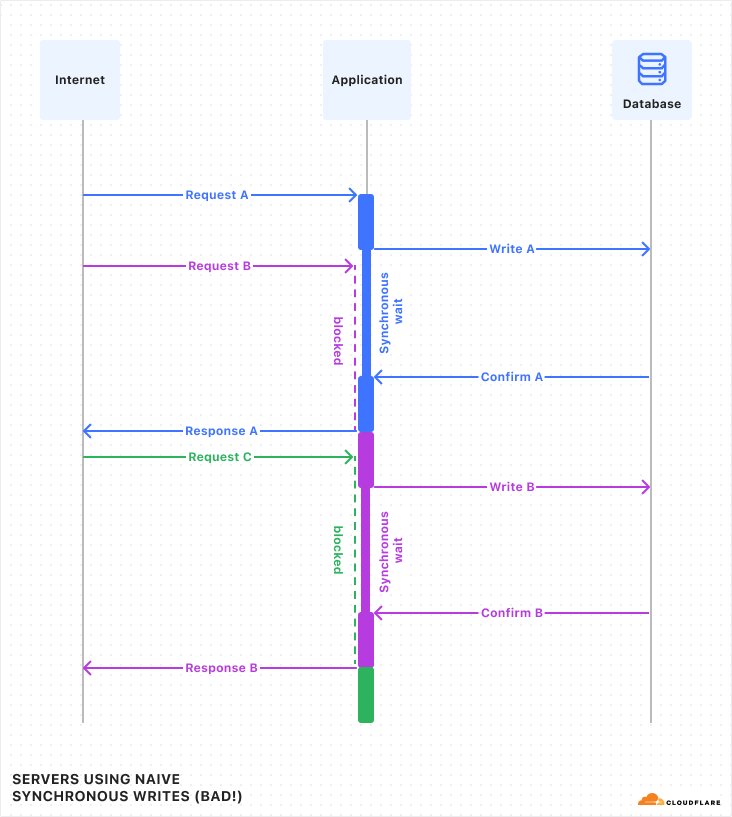
But I just told you that in Durable Objects, writes are synchronous. While a synchronous call is running, no other code in the program can run (because JavaScript does not have threads). This is convenient, as mentioned above, because it means you don’t need to worry that the state of the world may have changed while you were waiting. However, if write queries have to wait a while, and the whole program must pause and wait for them, then throughput will suffer.


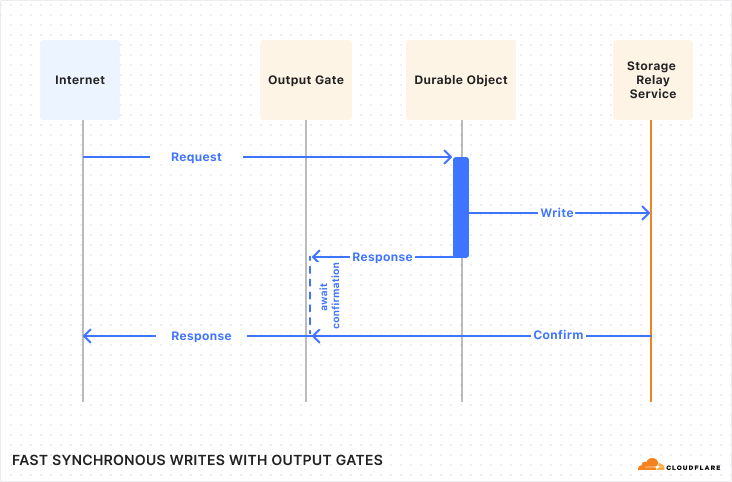
Luckily, in Durable Objects, writes do not have to wait, due to a little trick we call “Output Gates”.


In DOs, when the application issues a write, it continues executing without waiting for confirmation. However, when the DO then responds to the client, the response is blocked by the “Output Gate”. This system holds the response until all storage writes relevant to the response have been confirmed, then sends the response on its way. In the rare case that the write fails, the response will be replaced with an error and the Durable Object itself will restart. So, even though the application constructed a “success” response, nobody can ever see that this happened, and thus nobody can be misled into believing that the data was stored.

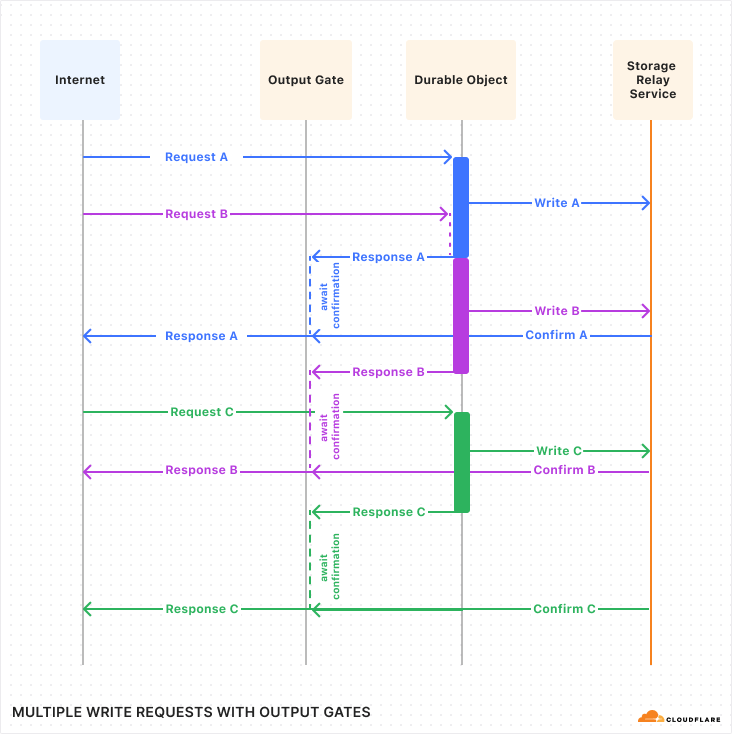
Let’s see what this looks like with multiple requests:


If you compare this against the first diagram above, you should notice a few things:

  • The timing of requests and confirmations are the same.

  • But, all responses were sent to the client sooner than in the first diagram. Latency was reduced! This is because the application is able to work on constructing the response in parallel with the storage layer confirming the write.

  • Request handling is no longer interleaved between the three requests. Instead, each request runs to completion before the next begins. The application does not need to worry, during the handling of one request, that its state might change unexpectedly due to a concurrent request.

With Output Gates, we get the ease-of-use of synchronous writes, while also getting lower latency and no loss of throughput.

N+1 selects? No problem.

Zero-latency queries aren’t just faster, they allow you to structure your code differently, often making it simpler. A classic example is the “N+1 selects” or “N+1 queries” problem. Let’s illustrate this problem with an example:

// N+1 SELECTs example

// Get the 100 most-recently-modified docs.
let docs = sql.exec(`
  SELECT title, authorId FROM documents
  ORDER BY lastModified DESC
  LIMIT 100
`).toArray();

// For each returned document, get the author name from the users table.
for (let doc of docs) {
  doc.authorName = sql.exec(
      "SELECT name FROM users WHERE id = ?", doc.authorId).one().name;
}

If you are an experienced SQL user, you are probably cringing at this code, and for good reason: this code does 101 queries! If the application is talking to the database across a network with 5ms latency, this will take 505ms to run, which is slow enough for humans to notice.

// Do it all in one query with a join?
let docs = sql.exec(`
  SELECT documents.title, users.name
  FROM documents JOIN users ON documents.authorId = users.id
  ORDER BY documents.lastModified DESC
  LIMIT 100
`).toArray();

Here we’ve used SQL features to turn our 101 queries into one query. Great! Except, what does it mean? We used an inner join, which is not to be confused with a left, right, or cross join. What’s the difference? Honestly, I have no idea! I had to look up joins just to write this example and I’m already confused.

Well, good news: You don’t need to figure it out. Because when using SQLite as a library, the first example above works just fine. It’ll perform about the same as the second fancy version.

More generally, when using SQLite as a library, you don’t have to learn how to do fancy things in SQL syntax. Your logic can be in regular old application code in your programming language of choice, orchestrating the most basic SQL queries that are easy to learn. It’s fine. The creators of SQLite have made this point themselves.

Point-in-Time Recovery

While not necessarily related to speed, SQLite-backed Durable Objects offer another feature: any object can be reverted to the state it had at any point in time in the last 30 days. So if you accidentally execute a buggy query that corrupts all your data, don’t worry: you can recover. There’s no need to opt into this feature in advance; it’s on by default for all SQLite-backed DOs. See the docs for details.

How do I use it?

Let’s say we’re an airline, and we are implementing a way for users to choose their seats on a flight. We will create a new Durable Object for each flight. Within that DO, we will use a SQL table to track the assignments of seats to passengers. The code might look something like this:

import {DurableObject} from "cloudflare:workers";

// Manages seat assignment for a flight.
//
// This is an RPC interface. The methods can be called remotely by other Workers
// running anywhere in the world. All Workers that specify same object ID
// (probably based on the flight number and date) will reach the same instance of
// FlightSeating.
export class FlightSeating extends DurableObject {
  sql = this.ctx.storage.sql;

  // Application calls this when the flight is first created to set up the seat map.
  initializeFlight(seatList) {
    this.sql.exec(`
      CREATE TABLE seats (
        seatId TEXT PRIMARY KEY,  -- e.g. "3B"
        occupant TEXT             -- null if available
      )
    `);

    for (let seat of seatList) {
      this.sql.exec(`INSERT INTO seats VALUES (?, null)`, seat);
    }
  }

  // Get a list of available seats.
  getAvailable() {
    let results = [];

    // Query returns a cursor.
    let cursor = this.sql.exec(`SELECT seatId FROM seats WHERE occupant IS NULL`);

    // Cursors are iterable.
    for (let row of cursor) {
      // Each row is an object with a property for each column.
      results.push(row.seatId);
    }

    return results;
  }

  // Assign passenger to a seat.
  assignSeat(seatId, occupant) {
    // Check that seat isn't occupied.
    let cursor = this.sql.exec(`SELECT occupant FROM seats WHERE seatId = ?`, seatId);
    let result = [...cursor][0];  // Get the first result from the cursor.
    if (!result) {
      throw new Error("No such seat: " + seatId);
    }
    if (result.occupant !== null) {
      throw new Error("Seat is occupied: " + seatId);
    }

    // If the occupant is already in a different seat, remove them.
    this.sql.exec(`UPDATE seats SET occupant = null WHERE occupant = ?`, occupant);

    // Assign the seat. Note: We don't have to worry that a concurrent request may
    // have grabbed the seat between the two queries, because the code is synchronous
    // (no `await`s) and the database is private to this Durable Object. Nothing else
    // could have changed since we checked that the seat was available earlier!
    this.sql.exec(`UPDATE seats SET occupant = ? WHERE seatId = ?`, occupant, seatId);
  }
}

(With just a little more code, we could extend this example to allow clients to subscribe to seat changes with WebSockets, so that if multiple people are choosing their seats at the same time, they can see in real time as seats become unavailable. But, that’s outside the scope of this blog post, which is just about SQL storage.)

Then in wrangler.toml, define a migration setting up your DO class like usual, but instead of using new_classes, use new_sqlite_classes:

[[migrations]]
tag = "v1"
new_sqlite_classes = ["FlightSeating"]

SQLite-backed objects also support the existing key/value-based storage API: KV data is stored into a hidden table in the SQLite database. So, existing applications built on DOs will work when deployed using SQLite-backed objects.

However, because SQLite-backed objects are based on an all-new storage backend, it is currently not possible to switch an existing deployed DO class to use SQLite. You must ask for SQLite when initially deploying the new DO class; you cannot change it later. We plan to begin migrating existing DOs to the new storage backend in 2025.

Pricing

We’ve kept pricing for SQLite-in-DO similar to D1, Cloudflare’s serverless SQL database, by billing for SQL queries (based on rows) and SQL storage. SQL storage per object is limited to 1 GB during the beta period, and will be increased to 10 GB on general availability. DO requests and duration billing are unchanged and apply to all DOs regardless of storage backend. 

During the initial beta, billing is not enabled for SQL queries (rows read and rows written) and SQL storage. SQLite-backed objects will incur charges for requests and duration. We plan to enable SQL billing in the first half of 2025 with advance notice.

Workers Paid
Rows read First 25 billion / month included + $0.001 / million rows
Rows written First 50 million / month included + $1.00 / million rows
SQL storage 5 GB-month + $0.20/ GB-month

For more on how to use SQLite-in-Durable Objects, check out the documentation

What about D1?

Cloudflare Workers already offers another SQLite-backed database product: D1. In fact, D1 is itself built on SQLite-in-DO. So, what’s the difference? Why use one or the other?

In short, you should think of D1 as a more “managed” database product, while SQLite-in-DO is more of a lower-level “compute with storage” building block.

D1 fits into a more traditional cloud architecture, where stateless application servers talk to a separate database over the network. Those application servers are typically Workers, but could also be clients running outside of Cloudflare. D1 also comes with a pre-built HTTP API and managed observability features like query insights. With D1, where your application code and SQL database queries are not colocated like in SQLite-in-DO, Workers has Smart Placement to dynamically run your Worker in the best location to reduce total request latency, considering everything your Worker talks to, including D1. By the end of 2024, D1 will support automatic read replication for scalability and low-latency access around the world. If this managed model appeals to you, use D1.

Durable Objects require a bit more effort, but in return, give you more power. With DO, you have two pieces of code that run in different places: a front-end Worker which routes incoming requests from the Internet to the correct DO, and the DO itself, which runs on the same machine as the SQLite database. You may need to think carefully about which code to run where, and you may need to build some of your own tooling that exists out-of-the-box with D1. But because you are in full control, you can tailor the solution to your application’s needs and potentially achieve more.

Under the hood: Storage Relay Service

When Durable Objects first launched in 2020, it offered only a simple key/value-based interface for durable storage. Under the hood, these keys and values were stored in a well-known off-the-shelf database, with regional instances of this database deployed to locations in our data centers around the world. Durable Objects in each region would store their data to the regional database.

For SQLite-backed Durable Objects, we have completely replaced the persistence layer with a new system built from scratch, called Storage Relay Service, or SRS. SRS has already been powering D1 for over a year, and can now be used more directly by applications through Durable Objects.

SRS is based on a simple idea:

Local disk is fast and randomly-accessible, but expensive and prone to disk failures. Object storage (like R2) is cheap and durable, but much slower than local disk and not designed for database-like access patterns. Can we get the best of both worlds by using a local disk as a cache on top of object storage?

So, how does it work?

The mismatch in functionality between local disk and object storage

A SQLite database on disk tends to undergo many small changes in rapid succession. Any row of the database might be updated by any particular query, but the database is designed to avoid rewriting parts that didn’t change. Read queries may randomly access any part of the database. Assuming the right indexes exist to support the query, they should not require reading parts of the database that aren’t relevant to the results, and should complete in microseconds.

Object storage, on the other hand, is designed for an entirely different usage model: you upload an entire “object” (blob of bytes) at a time, and download an entire blob at a time. Each blob has a different name. For maximum efficiency, blobs should be fairly large, from hundreds of kilobytes to gigabytes in size. Latency is relatively high, measured in tens or hundreds of milliseconds.

So how do we back up our SQLite database to object storage? An obviously naive strategy would be to simply make a copy of the database files from time to time and upload it as a new “object”. But, uploading the database on every change — and making the application wait for the upload to complete — would obviously be way too slow. We could choose to upload the database only occasionally — say, every 10 minutes — but this means in the case of a disk failure, we could lose up to 10 minutes of changes. Data loss is, uh, bad! And even then, for most databases, it’s likely that most of the data doesn’t change every 10 minutes, so we’d be uploading the same data over and over again.

Trick one: Upload a log of changes

Instead of uploading the entire database, SRS records a log of changes, and uploads those.

Conveniently, SQLite itself already has a concept of a change log: the Write-Ahead Log, or WAL. SRS always configures SQLite to use WAL mode. In this mode, any changes made to the database are first written to a separate log file. From time to time, the database is “checkpointed”, merging the changes back into the main database file. The WAL format is well-documented and easy to understand: it’s just a sequence of “frames”, where each frame is an instruction to write some bytes to a particular offset in the database file.

SRS monitors changes to the WAL file (by hooking SQLite’s VFS to intercept file writes) to discover the changes being made to the database, and uploads those to object storage.

Unfortunately, SRS cannot simply upload every single change as a separate “object”, as this would result in too many objects, each of which would be inefficiently small. Instead, SRS batches changes over a period of up to 10 seconds, or up to 16 MB worth, whichever happens first, then uploads the whole batch as a single object.

When reconstructing a database from object storage, we must download the series of change batches and replay them in order. Of course, if the database has undergone many changes over a long period of time, this can get expensive. In order to limit how far back it needs to look, SRS also occasionally uploads a snapshot of the entire content of the database. SRS will decide to upload a snapshot any time that the total size of logs since the last snapshot exceeds the size of the database itself. This heuristic implies that the total amount of data that SRS must download to reconstruct a database is limited to no more than twice the size of the database. Since we can delete data from object storage that is older than the latest snapshot, this also means that our total stored data is capped to 2x the database size.

Credit where credit is due: This idea — uploading WAL batches and snapshots to object storage — was inspired by Litestream, although our implementation is different.

Trick two: Relay through other servers in our global network


Batches are only uploaded to object storage every 10 seconds. But obviously, we cannot make the application wait for 10 whole seconds just to confirm a write. So what happens if the application writes some data, returns a success message to the user, and then the machine fails 9 seconds later, losing the data?

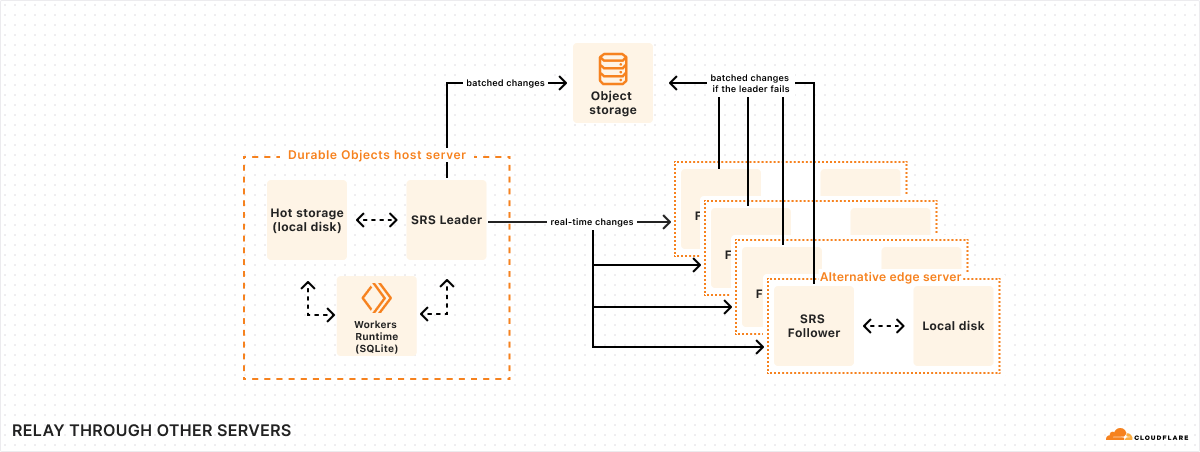
To solve this problem, we take advantage of our global network. Every time SQLite commits a transaction, SRS will immediately forward the change log to five “follower” machines across our network. Once at least three of these followers respond that they have received the change, SRS informs the application that the write is confirmed. (As discussed earlier, the write confirmation opens the Durable Object’s “output gate”, unblocking network communications to the rest of the world.)

When a follower receives a change, it temporarily stores it in a buffer on local disk, and then awaits further instructions. Later on, once SRS has successfully uploaded the change to object storage as part of a batch, it informs each follower that the change has been persisted. At that point, the follower can simply delete the change from its buffer.

However, if the follower never receives the persisted notification, then, after some timeout, the follower itself will upload the change to object storage. Thus, if the machine running the database suddenly fails, as long as at least one follower is still running, it will ensure that all confirmed writes are safely persisted.

Each of a database’s five followers is located in a different physical data center. Cloudflare’s network consists of hundreds of data centers around the world, which means it is always easy for us to find four other data centers nearby any Durable Object (in addition to the one it is running in). In order for a confirmed write to be lost, then, at least four different machines in at least three different physical buildings would have to fail simultaneously (three of the five followers, plus the Durable Object’s host machine). Of course, anything can happen, but this is exceedingly unlikely.

Followers also come in handy when a Durable Object’s host machine is unresponsive. We may not know for sure if the machine has died completely, or if it is still running and responding to some clients but not others. We cannot start up a new instance of the DO until we know for sure that the previous instance is dead – or, at least, that it can no longer confirm writes, since the old and new instances could then confirm contradictory writes. To deal with this situation, if we can’t reach the DO’s host, we can instead try to contact its followers. If we can contact at least three of the five followers, and tell them to stop confirming writes for the unreachable DO instance, then we know that instance is unable to confirm any more writes going forward. We can then safely start up a new instance to replace the unreachable one.

Bonus feature: Point-in-Time Recovery

I mentioned earlier that SQLite-backed Durable Objects can be asked to revert their state to any time in the last 30 days. How does this work?

This was actually an accidental feature that fell out of SRS’s design. Since SRS stores a complete log of changes made to the database, we can restore to any point in time by replaying the change log from the last snapshot. The only thing we have to do is make sure we don’t delete those logs too soon.

Normally, whenever a snapshot is uploaded, all previous logs and snapshots can then be deleted. But instead of deleting them immediately, SRS merely marks them for deletion 30 days later. In the meantime, if a point-in-time recovery is requested, the data is still there to work from.

For a database with a high volume of writes, this may mean we store a lot of data for a lot longer than needed. As it turns out, though, once data has been written at all, keeping it around for an extra month is pretty cheap — typically cheaper, even, than writing it in the first place. It’s a small price to pay for always-on disaster recovery.

Get started with SQLite-in-DO

SQLite-backed DOs are available in beta starting today. You can start building with SQLite-in-DO by visiting developer documentation and provide beta feedback via the #durable-objects channel on our Developer Discord.

Do distributed systems like SRS excite you? Would you like to be part of building them at Cloudflare? We’re hiring!

Cloudflare acquires PartyKit to allow developers to build real-time multi-user applications

Post Syndicated from Sunil Pai original https://blog.cloudflare.com/cloudflare-acquires-partykit


We’re thrilled to announce that PartyKit, an open source platform for deploying real-time, collaborative, multiplayer applications, is now a part of Cloudflare. This acquisition marks a significant milestone in our journey to redefine the boundaries of serverless computing, making it more dynamic, interactive, and, importantly, stateful.

Defining the future of serverless compute around state

Building real-time applications on the web have always been difficult. Not only is it a distributed systems problem, but you need to provision and manage infrastructure, databases, and other services to maintain state across multiple clients. This complexity has traditionally been a barrier to entry for many developers, especially those who are just starting out.

We announced Durable Objects in 2020 as a way of building synchronized real time experiences for the web. Unlike regular serverless functions that are ephemeral and stateless, Durable Objects are stateful, allowing developers to build applications that maintain state across requests. They also act as an ideal synchronization point for building real-time applications that need to maintain state across multiple clients. Combined with WebSockets, Durable Objects can be used to build a wide range of applications, from multiplayer games to collaborative drawing tools.

In 2022, PartyKit began as a project to further explore the capabilities of Durable Objects and make them more accessible to developers by exposing them through familiar components. In seconds, you could create a project that configured behavior for these objects, and deploy it to Cloudflare. By integrating with popular libraries such as Yjs (the gold standard in collaborative editing) and React, PartyKit made it possible for developers to build a wide range of use cases, from multiplayer games to collaborative drawing tools, into their applications.

Building experiences with real-time components was previously only accessible to multi-billion dollar companies, but new computing primitives like Durable Objects on the edge make this accessible to regular developers and teams. With PartyKit now under our roof, we’re doubling down on our commitment to this future — a future where serverless is stateful.

We’re excited to give you a preview into our shared vision for applications, and the use cases we’re excited to simplify together.

Making state for serverless easy

Unlike conventional approaches that rely on external databases to maintain state, thereby complicating scalability and increasing costs, PartyKit leverages Cloudflare’s Durable Objects to offer a seamless model where stateful serverless functions can operate as if they were running on a single machine, maintaining state across requests. This innovation not only simplifies development but also opens up a broader range of use cases, including real-time computing, collaborative editing, and multiplayer gaming, by allowing thousands of these “machines” to be spun up globally, each maintaining its own state. PartyKit aims to be a complement to traditional serverless computing, providing a more intuitive and efficient method for developing applications that require stateful behavior, thereby marking the “next evolution” of serverless computing.

Simplifying WebSockets for Real-Time Interaction

WebSockets have revolutionized how we think about bidirectional communication on the web. Yet, the challenge has always been about scaling these interactions to millions without a hitch. Cloudflare Workers step in as the hero, providing a serverless framework that makes real-time applications like chat services, multiplayer games, and collaborative tools not just possible but scalable and efficient.

Powering Games and Multiplayer Applications Without Limits

Imagine building multiplayer platforms where the game never lags, the collaboration is seamless, and video conferences are crystal clear. Cloudflare’s Durable Objects morph the stateless serverless landscape into a realm where persistent connections thrive. PartyKit’s integration into this ecosystem means developers now have a powerhouse toolkit to bring ambitious multiplayer visions to life, without the traditional overheads.

This is especially critical in gaming — there are few areas where low-latency and real-time interaction matter more. Every millisecond, every lag, every delay defines the entire experience. With PartyKit’s capabilities integrated into Cloudflare, developers will be able to leverage our combined technologies to create gaming experiences that are not just about playing but living the game, thanks to scalable, immersive, and interactive platforms.

The toolkit for building Local-First applications

The Internet is great, and increasingly always available, but there are still a few situations where we are forced to disconnect — whether on a plane, a train, or a beach.

The premise of local-first applications is that work doesn’t stop when the Internet does. Wherever you left off in your doc, you can keep working on it, assuming the state will be restored when you come back online. By storing data on the client and syncing when back online, these applications offer resilience and responsiveness that’s unmatched. Cloudflare’s vision, enhanced by PartyKit’s technology, aims to make local-first not just an option but the standard for application development.

What’s next for PartyKit users?

Users can expect their existing projects to continue working as expected. We will be adding more features to the platform, including the ability to create and use PartyKit projects inside existing Workers and Pages projects. There will be no extra charges to use PartyKit for commercial purposes, other than the standard usage charges for Cloudflare Workers and other services. Further, we’re going to expand the roadmap to begin working on integrations with popular frameworks and libraries, such as React, Vue, and Angular. We’re deeply committed to executing on the PartyKit vision and roadmap, and we’re excited to see what you build with it.

The Beginning of a New Chapter

The acquisition of PartyKit by Cloudflare isn’t just a milestone for our two teams; it’s a leap forward for developers everywhere. Together, we’re not just building tools; we’re crafting the foundation for the next generation of Internet applications. The future of serverless is stateful, and with PartyKit’s expertise now part of our arsenal, we’re more ready than ever to make that future a reality.

Welcome to the Cloudflare team, PartyKit. Look forward to building something remarkable together.

Running Serverless Puppeteer with Workers and Durable Objects

Post Syndicated from Tanushree Sharma original http://blog.cloudflare.com/running-serverless-puppeteer-workers-durable-objects/

Running Serverless Puppeteer with Workers and Durable Objects

Running Serverless Puppeteer with Workers and Durable Objects

Last year, we announced the Browser Rendering API – letting users running Puppeteer, a browser automation library, directly in Workers. Puppeteer is one of the most popular libraries used to interact with a headless browser instance to accomplish tasks like taking screenshots, generating PDFs, crawling web pages, and testing web applications. We’ve heard from developers that configuring and maintaining their own serverless browser automation systems can be quite painful.

The Workers Browser Rendering API solves this. It makes the Puppeteer library available directly in your Worker, connected to a real web browser, without the need to configure and manage infrastructure or keep browser sessions warm yourself. You can use @cloudflare/puppeteer to run the full Puppeteer API directly on Workers!

We’ve seen so much interest from the developer community since launching last year. While the Browser Rendering API is still in beta (sign up to our waitlist to get access), we wanted to share a way to get more out of our current limits by using the Browser Rendering API with Durable Objects. We’ll also be sharing pricing for the Rendering API, so you can build knowing exactly what you’ll pay for.

Building a responsive web design testing tool with the Browser Rendering API

As a designer or frontend developer, you want to make sure that content is well-designed for visitors browsing on different screen sizes. With the number of possible devices that users are browsing on are growing, it becomes difficult to test all the possibilities manually. While there are many testing tools on the market, we want to show how easy it is to create your own Chromium based tool with the Workers Browser Rendering API and Durable Objects.

Running Serverless Puppeteer with Workers and Durable Objects

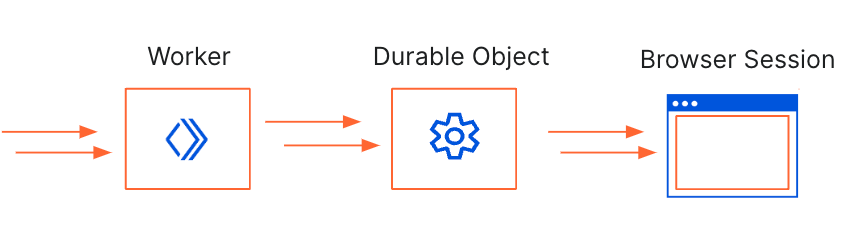
We’ll be using the Worker to handle any incoming requests, pass them to the Durable Object to take screenshots and store them in an R2 bucket. The Durable Object is used to create a browser session that’s persistent. By using Durable Object Alarms we can keep browsers open for longer and reuse browser sessions across requests.

Let’s dive into how we can build this application:

  1. Create a Worker with a Durable Object, Browser Rendering API binding and R2 bucket. This is the resulting wrangler.toml:
name = "rendering-api-demo"
main = "src/index.js"
compatibility_date = "2023-09-04"
compatibility_flags = [ "nodejs_compat"]
account_id = "c05e6a39aa4ccdd53ad17032f8a4dc10"


# Browser Rendering API binding
browser = { binding = "MYBROWSER" }

# Bind an R2 Bucket
[[r2_buckets]]
binding = "BUCKET"
bucket_name = "screenshots"

# Binding to a Durable Object
[[durable_objects.bindings]]
name = "BROWSER"
class_name = "Browser"

[[migrations]]
tag = "v1" # Should be unique for each entry
new_classes = ["Browser"] # Array of new classes

2. Define the Worker

This Worker simply passes the request onto the Durable Object.

export default {
	async fetch(request, env) {

		let id = env.BROWSER.idFromName("browser");
		let obj = env.BROWSER.get(id);
	  
		// Send a request to the Durable Object, then await its response.
		let resp = await obj.fetch(request.url);
		let count = await resp.text();
	  
		return new Response("success");
	}
};

3. Define the Durable Object class

const KEEP_BROWSER_ALIVE_IN_SECONDS = 60;

export class Browser {
	constructor(state, env) {
		this.state = state;
		this.env = env;
		this.keptAliveInSeconds = 0;
		this.storage = this.state.storage;
	}
  
	async fetch(request) {
		// screen resolutions to test out
		const width = [1920, 1366, 1536, 360, 414]
		const height = [1080, 768, 864, 640, 896]

		// use the current date and time to create a folder structure for R2
		const nowDate = new Date()
		var coeff = 1000 * 60 * 5
		var roundedDate = (new Date(Math.round(nowDate.getTime() / coeff) * coeff)).toString();
		var folder = roundedDate.split(" GMT")[0]

		//if there's a browser session open, re-use it
		if (!this.browser) {
			console.log(`Browser DO: Starting new instance`);
			try {
			  this.browser = await puppeteer.launch(this.env.MYBROWSER);
			} catch (e) {
			  console.log(`Browser DO: Could not start browser instance. Error: ${e}`);
			}
		  }
		
		// Reset keptAlive after each call to the DO
		this.keptAliveInSeconds = 0;
		
		const page = await this.browser.newPage();

		// take screenshots of each screen size 
		for (let i = 0; i < width.length; i++) {
			await page.setViewport({ width: width[i], height: height[i] });
			await page.goto("https://workers.cloudflare.com/");
			const fileName = "screenshot_" + width[i] + "x" + height[i]
			const sc = await page.screenshot({
				path: fileName + ".jpg"
			}
			);

			this.env.BUCKET.put(folder + "/"+ fileName + ".jpg", sc);
		  }
		
		// Reset keptAlive after performing tasks to the DO.
		this.keptAliveInSeconds = 0;

		// set the first alarm to keep DO alive
		let currentAlarm = await this.storage.getAlarm();
		if (currentAlarm == null) {
		console.log(`Browser DO: setting alarm`);
		const TEN_SECONDS = 10 * 1000;
		this.storage.setAlarm(Date.now() + TEN_SECONDS);
		}
		
		await this.browser.close();
		return new Response("success");
	}

	async alarm() {
		this.keptAliveInSeconds += 10;
	
		// Extend browser DO life
		if (this.keptAliveInSeconds < KEEP_BROWSER_ALIVE_IN_SECONDS) {
		  console.log(`Browser DO: has been kept alive for ${this.keptAliveInSeconds} seconds. Extending lifespan.`);
		  this.storage.setAlarm(Date.now() + 10 * 1000);
		} else console.log(`Browser DO: cxceeded life of ${KEEP_BROWSER_ALIVE_IN_SECONDS}. Browser DO will be shut down in 10 seconds.`);
	  }

  }

That’s it! With less than a hundred lines of code, you can fully customize a powerful tool to automate responsive web design testing. You can even incorporate it into your CI pipeline to automatically test different window sizes with each build and verify the result is as expected by using an automated library like pixelmatch.

How much will this cost?

We’ve spoken to many customers deploying a Puppeteer service on their own infrastructure, on public cloud containers or functions or using managed services. The common theme that we’ve heard is that these services are costly – costly to maintain and expensive to run.

While you won’t be billed for the Browser Rendering API yet, we want to be transparent with you about costs you start building. We know it’s important to understand the pricing structure so that you don’t get a surprise bill and so that you can design your application efficiently.

Running Serverless Puppeteer with Workers and Durable Objects

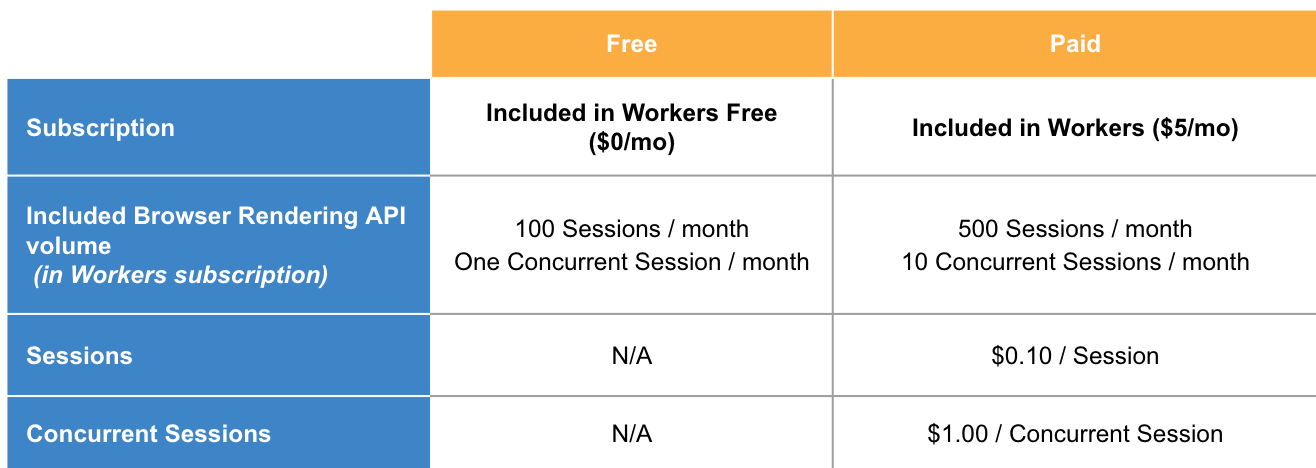
You pay based on two usage metrics:

  1. Number of sessions: A Browser Session is a new instance of a browser being launched
  2. Number of concurrent sessions: Concurrent Sessions is the number of browser instances open at once

Using Durable Objects to persist browser sessions improves performance by eliminating the time that it takes to spin up a new browser session. Since it re-uses sessions, it cuts down on the number of concurrent sessions needed. We highly encourage this model of session re-use if you expect to see consistent traffic for applications that you build on the Browser Rendering API.

If you have feedback about this pricing, we’re all ears. Feel free to reach out through Discord (channel name: browser-rendering-api-beta) and share your thoughts.

Get Started

Sign up to our waitlist to get access to the Workers Browser Rendering API. We’re so excited to see what you build! Share your creations with us on Twitter/X @CloudflareDev or on our Discord community.

How Waiting Room makes queueing decisions on Cloudflare’s highly distributed network

Post Syndicated from George Thomas original http://blog.cloudflare.com/how-waiting-room-queues/

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

Almost three years ago, we launched Cloudflare Waiting Room to protect our customers’ sites from overwhelming spikes in legitimate traffic that could bring down their sites. Waiting Room gives customers control over user experience even in times of high traffic by placing excess traffic in a customizable, on-brand waiting room, dynamically admitting users as spots become available on their sites. Since the launch of Waiting Room, we’ve continued to expand its functionality based on customer feedback with features like mobile app support, analytics, Waiting Room bypass rules, and more.

We love announcing new features and solving problems for our customers by expanding the capabilities of Waiting Room. But, today, we want to give you a behind the scenes look at how we have evolved the core mechanism of our product–namely, exactly how it kicks in to queue traffic in response to spikes.

How was the Waiting Room built, and what are the challenges?

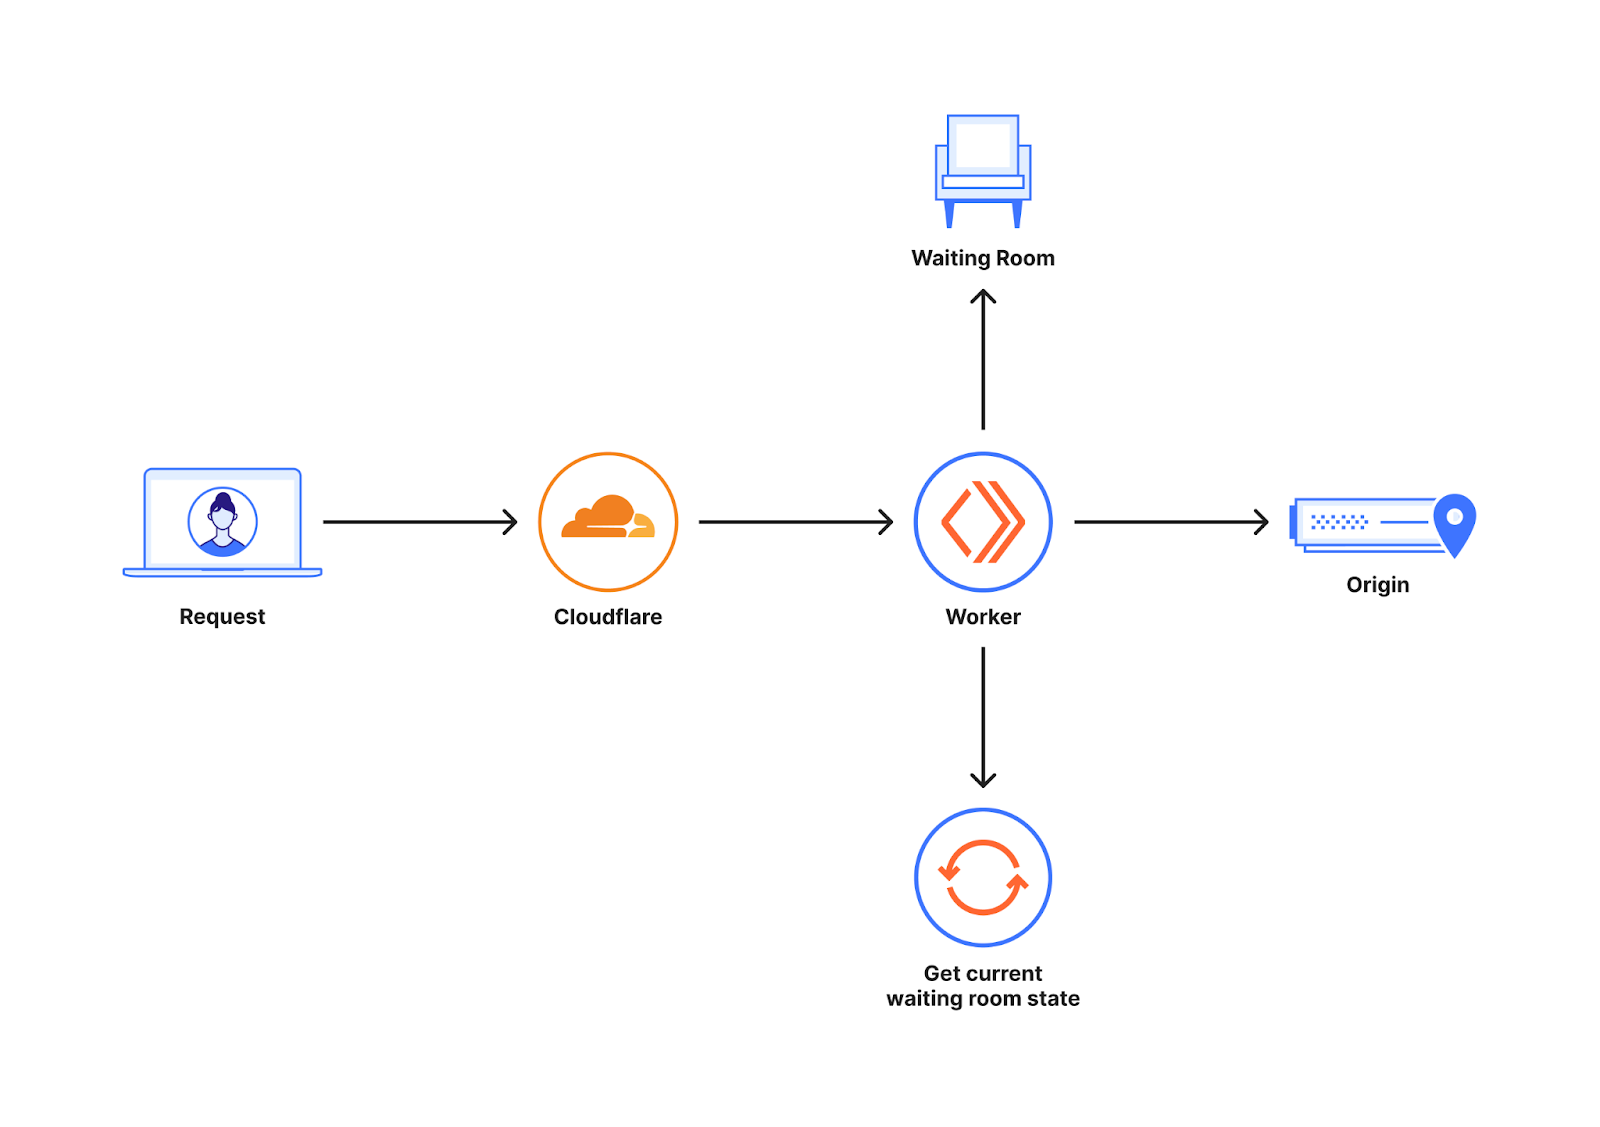
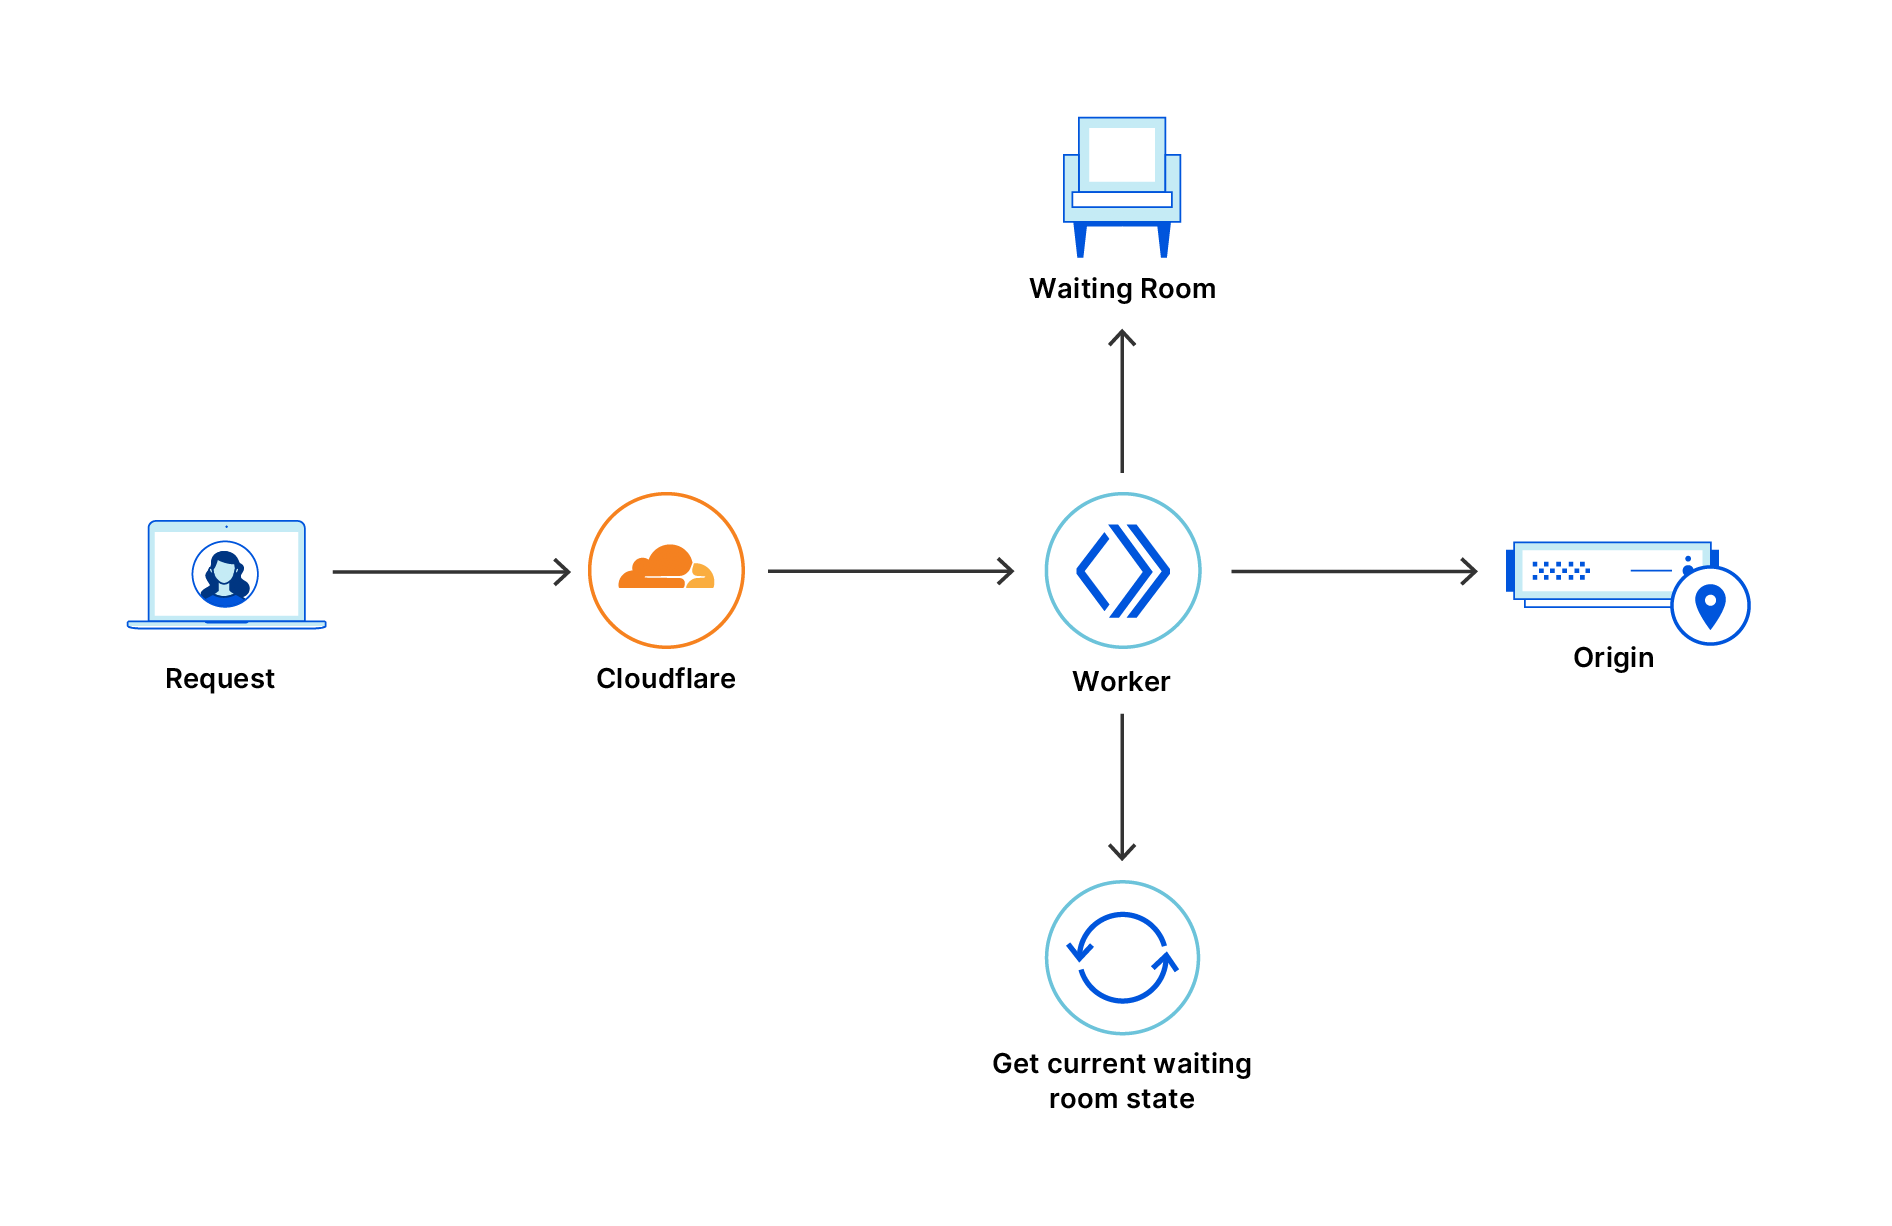
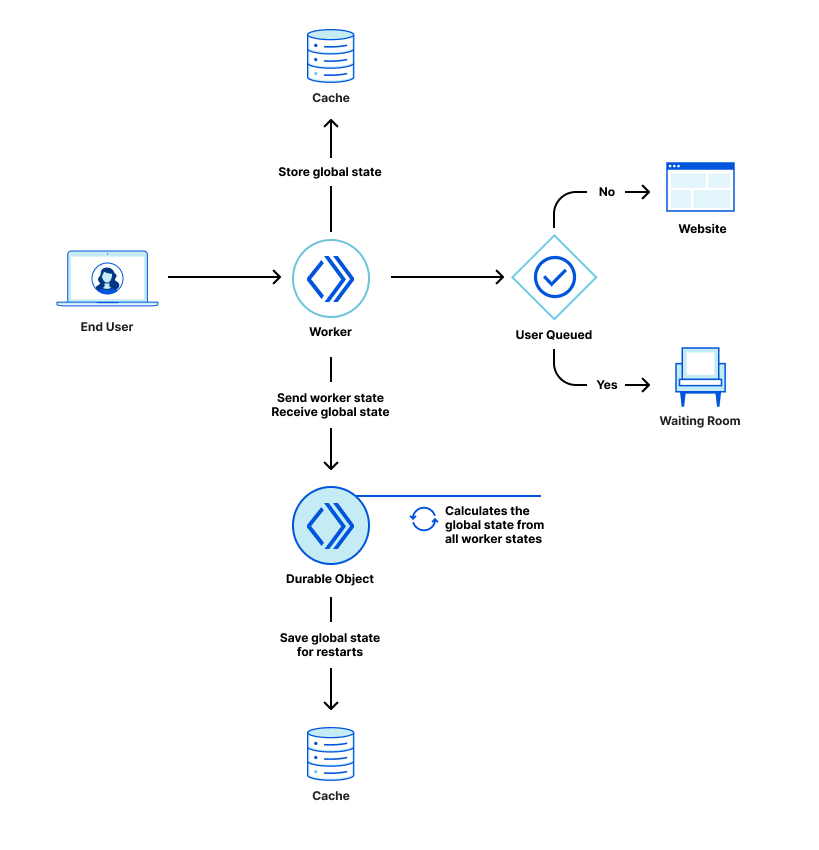
The diagram below shows a quick overview of where the Waiting room sits when a customer enables it for their website.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

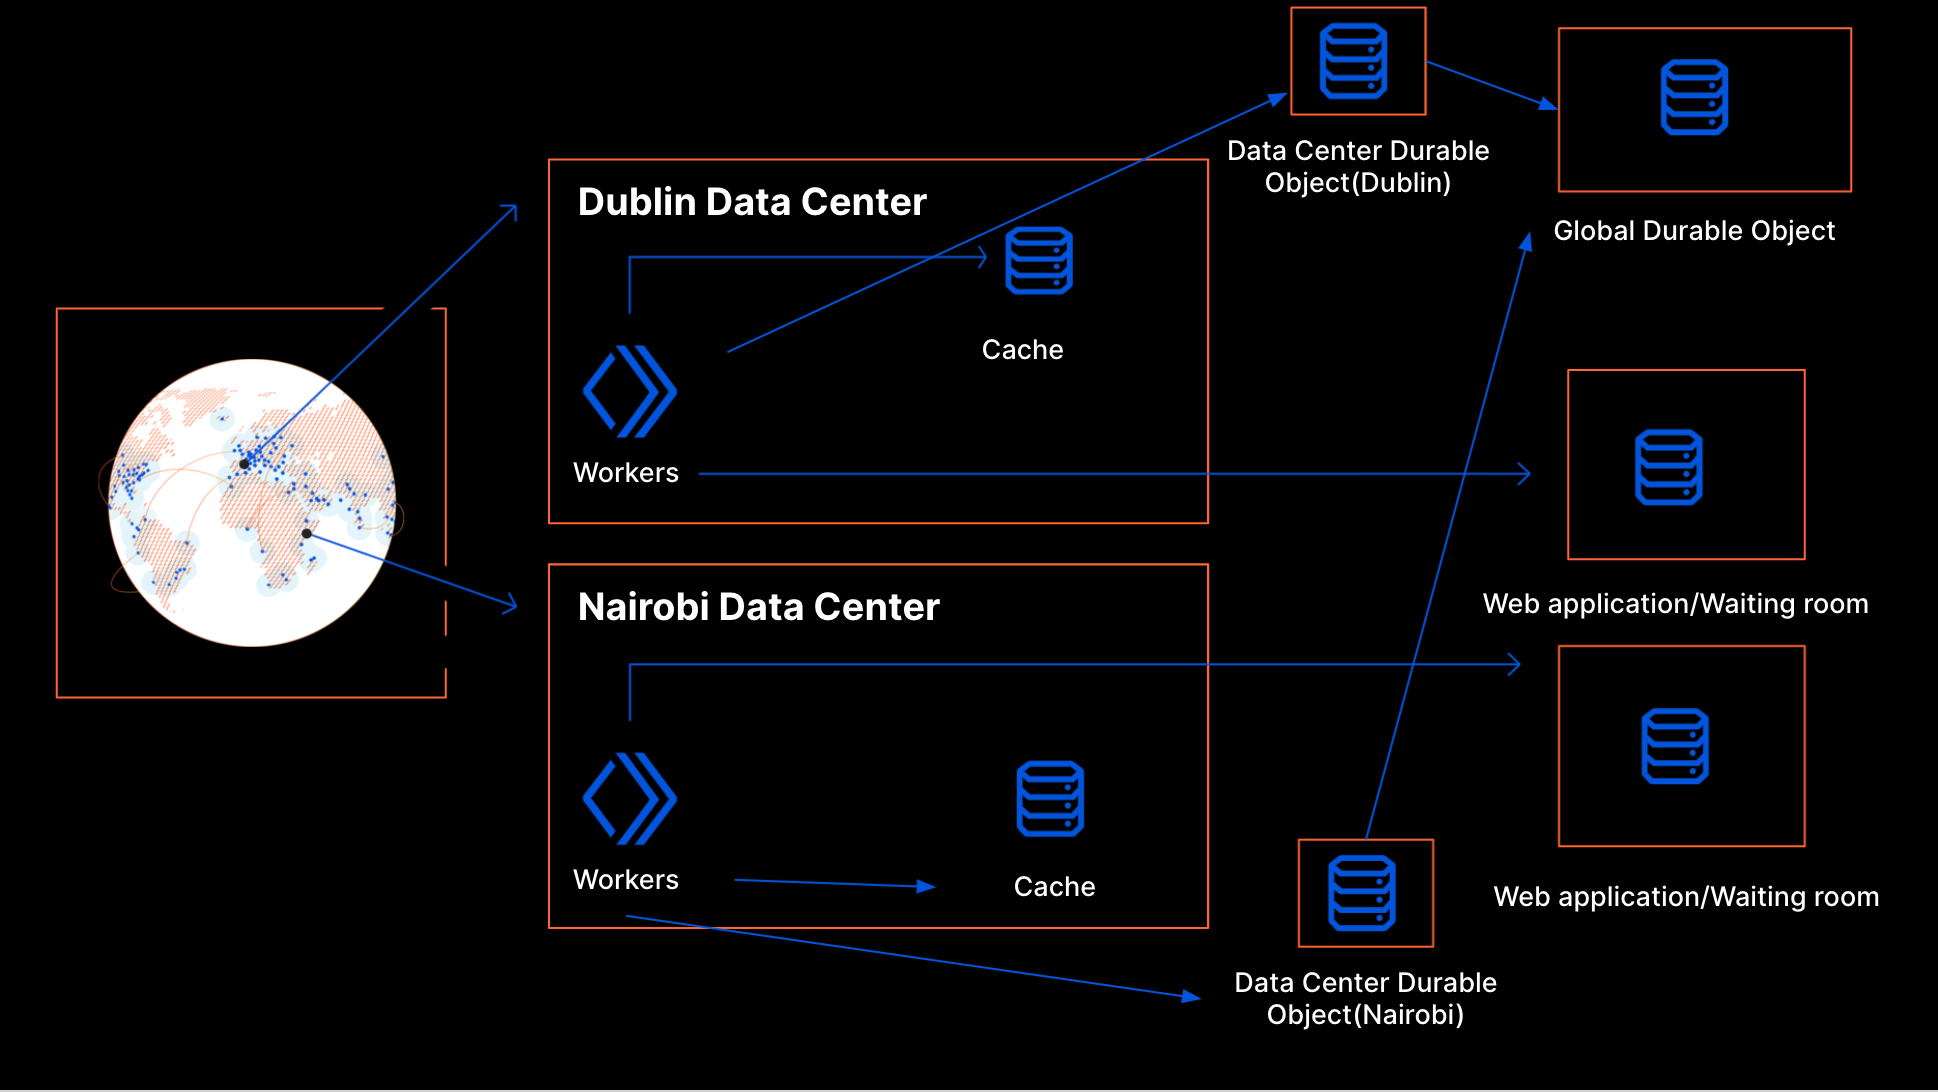
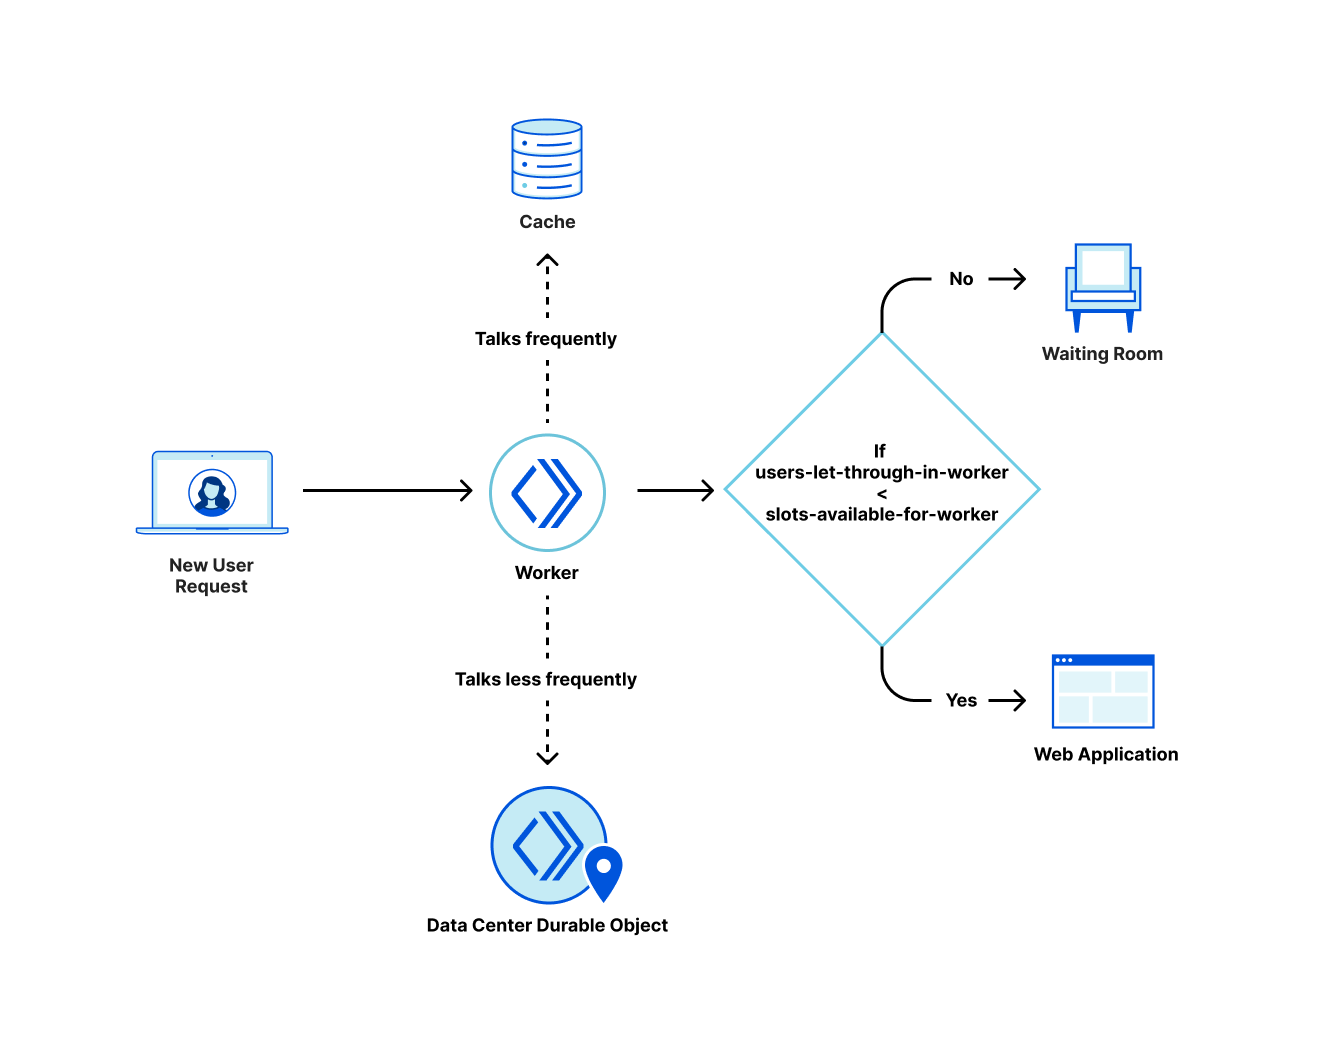
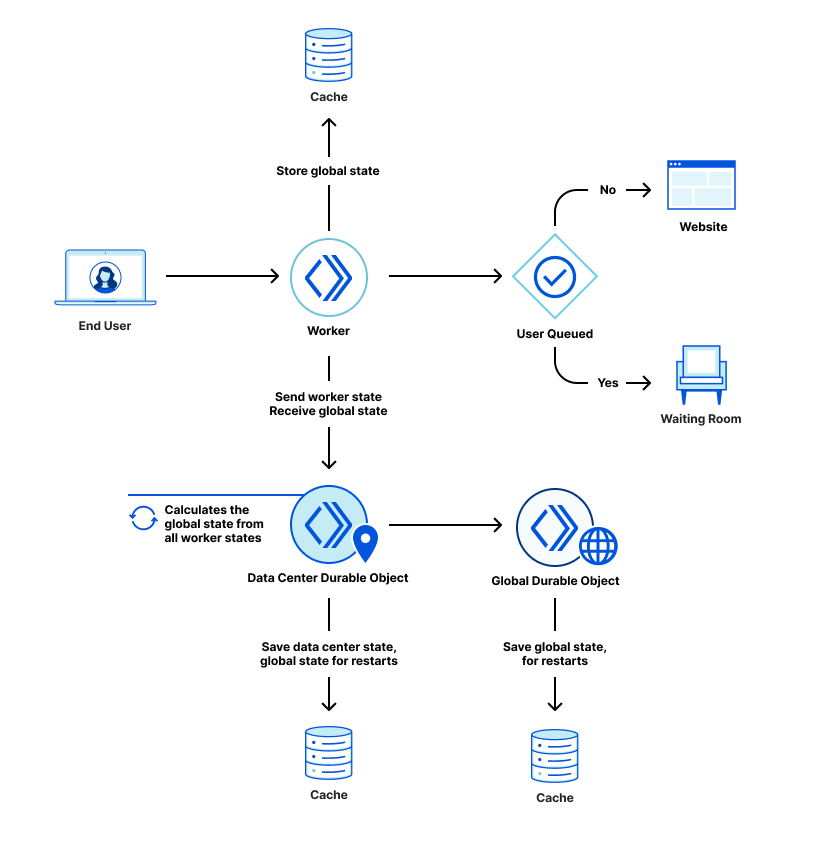
Waiting Room is built on Workers that runs across a global network of Cloudflare data centers. The requests to a customer’s website can go to many different Cloudflare data centers. To optimize for minimal latency and enhanced performance, these requests are routed to the data center with the most geographical proximity. When a new user makes a request to the host/path covered by the Waiting room, the waiting room worker decides whether to send the user to the origin or the waiting room. This decision is made by making use of the waiting room state which gives an idea of how many users are on the origin.

The waiting room state changes continuously based on the traffic around the world. This information can be stored in a central location or changes can get propagated around the world eventually. Storing this information in a central location can add significant latency to each request as the central location can be really far from where the request is originating from. So every data center works with its own waiting room state which is a snapshot of the traffic pattern for the website around the world available at that point in time. Before letting a user into the website, we do not want to wait for information from everywhere else in the world as that adds significant latency to the request. This is the reason why we chose not to have a central location but have a pipeline where changes in traffic get propagated eventually around the world.

This pipeline which aggregates the waiting room state in the background is built on Cloudflare Durable Objects. In 2021, we wrote a blog talking about how the aggregation pipeline works and the different design decisions we took there if you are interested. This pipeline ensures that every data center gets updated information about changes in traffic within a few seconds.

The Waiting room has to make a decision whether to send users to the website or queue them based on the state that it currently sees. This has to be done while making sure we queue at the right time so that the customer's website does not get overloaded. We also have to make sure we do not queue too early as we might be queueing for a falsely suspected spike in traffic. Being in a queue could cause some users to abandon going to the website. Waiting Room runs on every server in Cloudflare’s network, which spans over 300 cities in more than 100 countries. We want to make sure, for every new user, the decision whether to go to the website or the queue is made with minimal latency. This is what makes the decision of when to queue a hard question for the waiting room. In this blog, we will cover how we approached that tradeoff. Our algorithm has evolved to decrease the false positives while continuing to respect the customer’s set limits.

How a waiting room decides when to queue users

The most important factor that determines when your waiting room will start queuing is how you configured the traffic settings. There are two traffic limits that you will set when configuring a waiting room–total active users and new users per minute.The total active users is a target threshold for how many simultaneous users you want to allow on the pages covered by your waiting room. New users per minute defines the target threshold for the maximum rate of user influx to your website per minute. A sharp spike in either of these values might result in queuing. Another configuration that affects how we calculate the total active users is session duration. A user is considered active for session duration minutes since the request is made to any page covered by a waiting room.

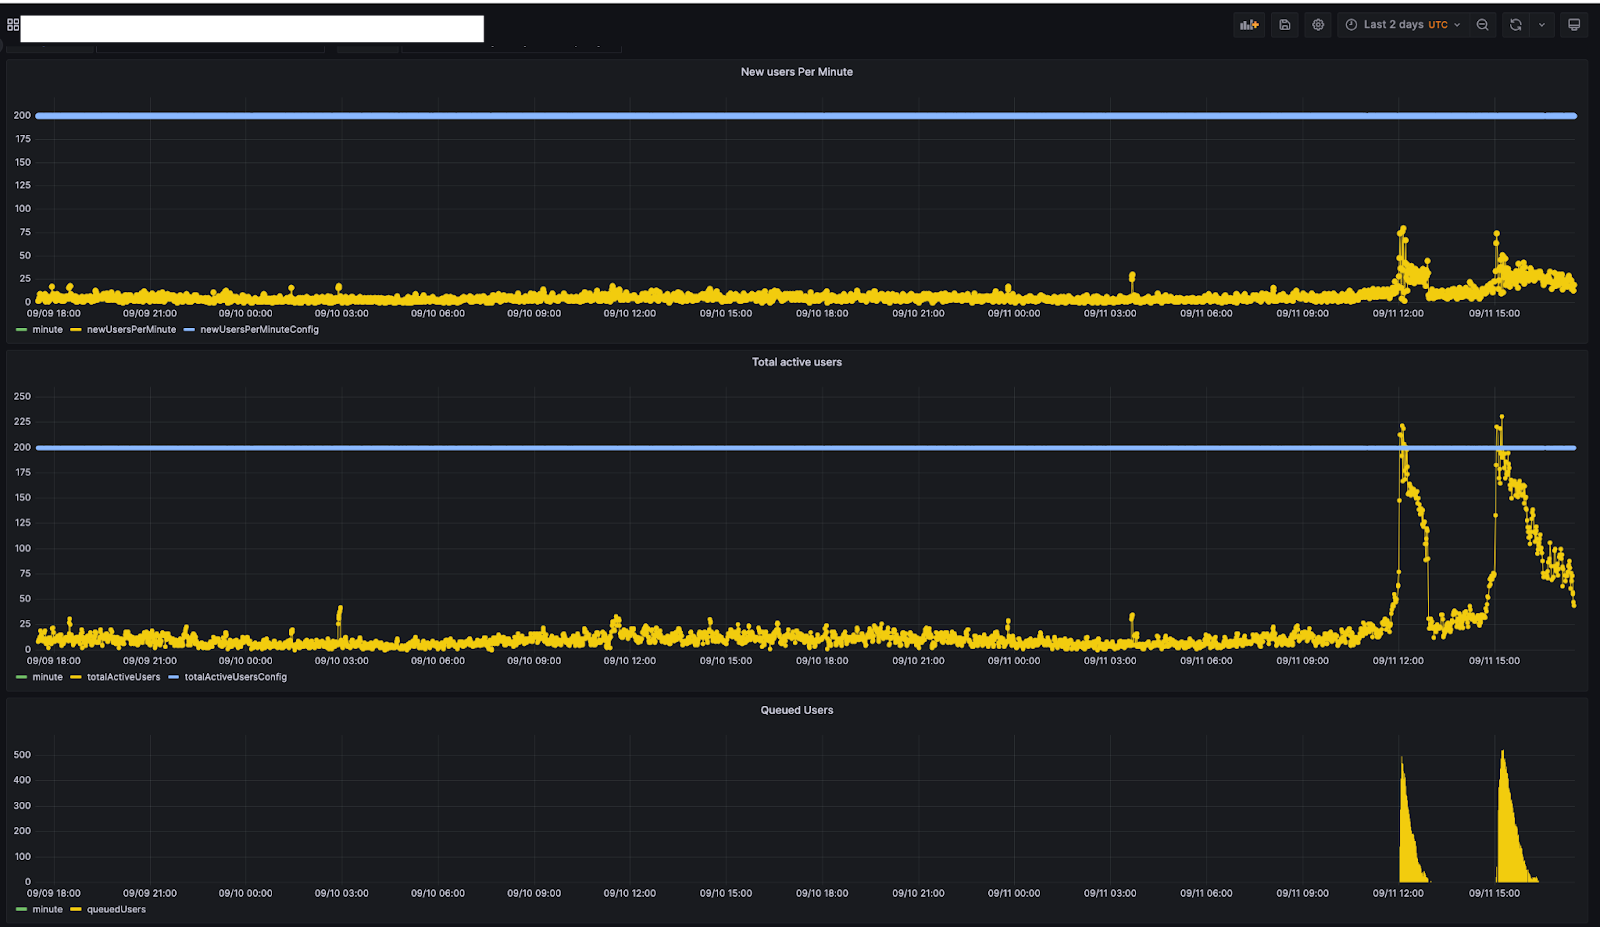
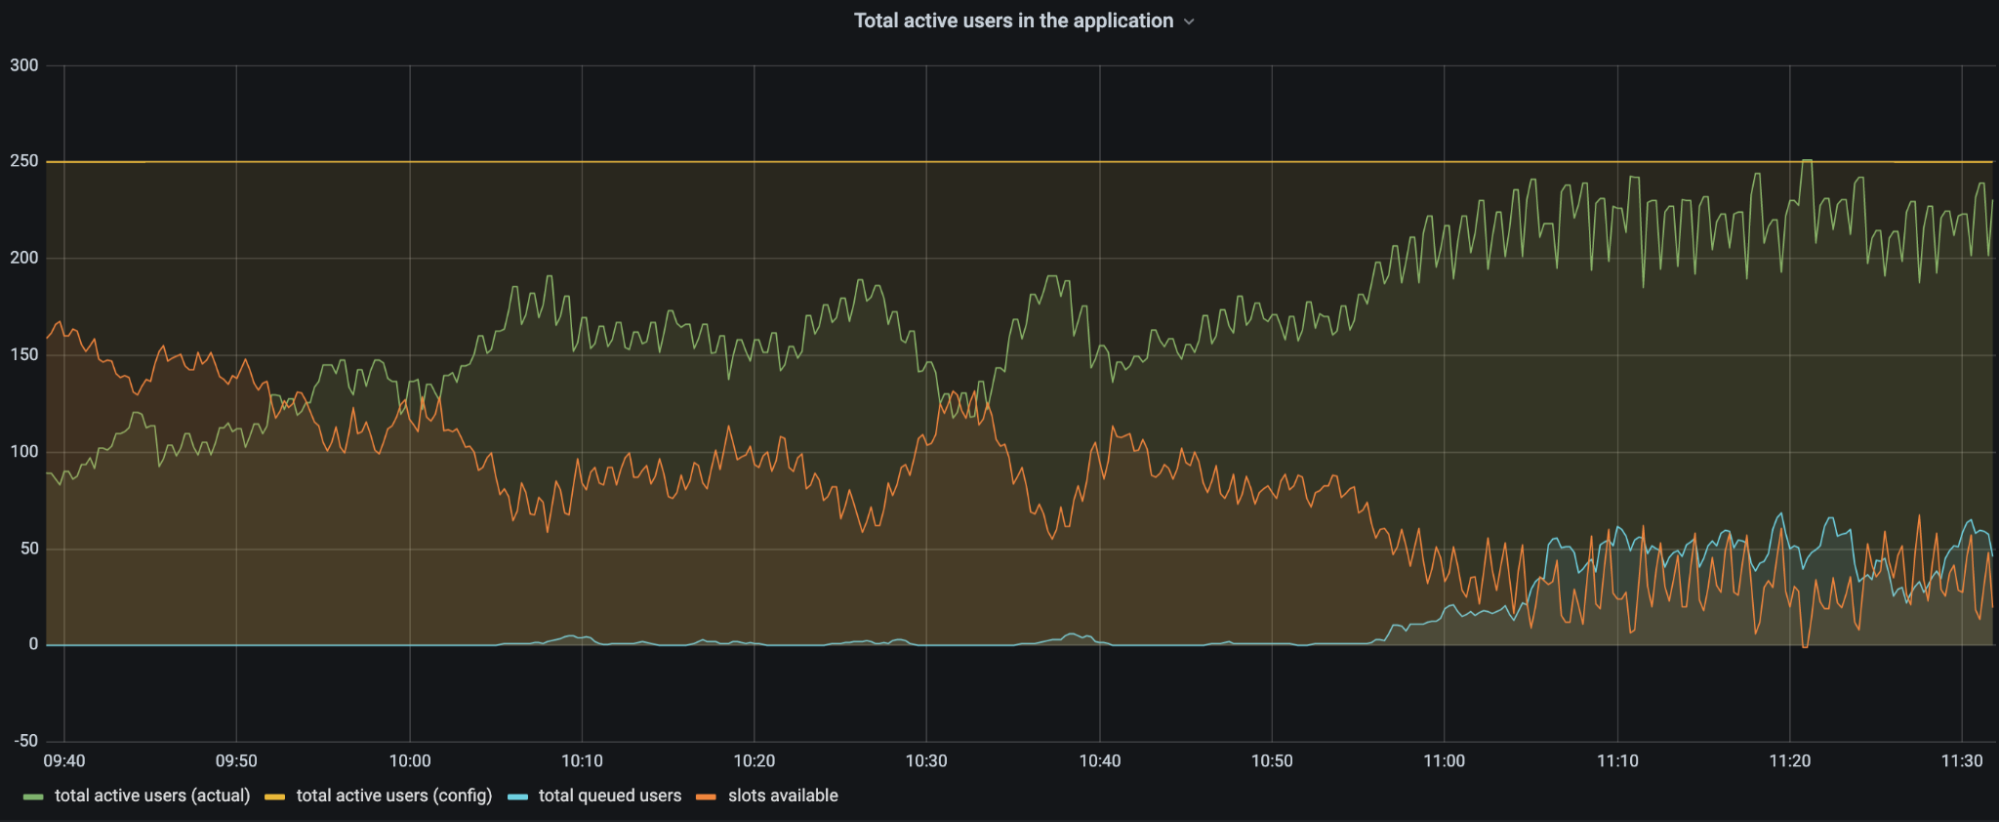
The graph below is from one of our internal monitoring tools for a customer and shows a customer's traffic pattern for 2 days. This customer has set their limits, new users per minute and total active users to 200 and 200 respectively.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

If you look at their traffic you can see that users were queued on September 11th around 11:45. At that point in time, the total active users was around 200. As the total active users ramped down (around 12:30), the queued users progressed to 0. The queueing started again on September 11th around 15:00 when total active users got to 200. The users that were queued around this time ensured that the traffic going to the website is around the limits set by the customer.

Once a user gets access to the website, we give them an encrypted cookie which indicates they have already gained access. The contents of the cookie can look like this.

{  
  "bucketId": "Mon, 11 Sep 2023 11:45:00 GMT",
  "lastCheckInTime": "Mon, 11 Sep 2023 11:45:54 GMT",
  "acceptedAt": "Mon, 11 Sep 2023 11:45:54 GMT"
}

The cookie is like a ticket which indicates entry to the waiting room.The bucketId indicates which cluster of users this user is part of. The acceptedAt time and lastCheckInTime indicate when the last interaction with the workers was. This information can ensure if the ticket is valid for entry or not when we compare it with the session duration value that the customer sets while configuring the waiting room. If the cookie is valid, we let the user through which ensures users who are on the website continue to be able to browse the website. If the cookie is invalid, we create a new cookie treating the user as a new user and if there is queueing happening on the website they get to the back of the queue. In the next section let us see how we decide when to queue those users.

To understand this further, let's see what the contents of the waiting room state are. For the customer we discussed above, at the time "Mon, 11 Sep 2023 11:45:54 GMT", the state could look like this.

{  
  "activeUsers": 50,
}

As mentioned above the customer’s configuration has new users per minute and total active users equal to 200 and 200 respectively.

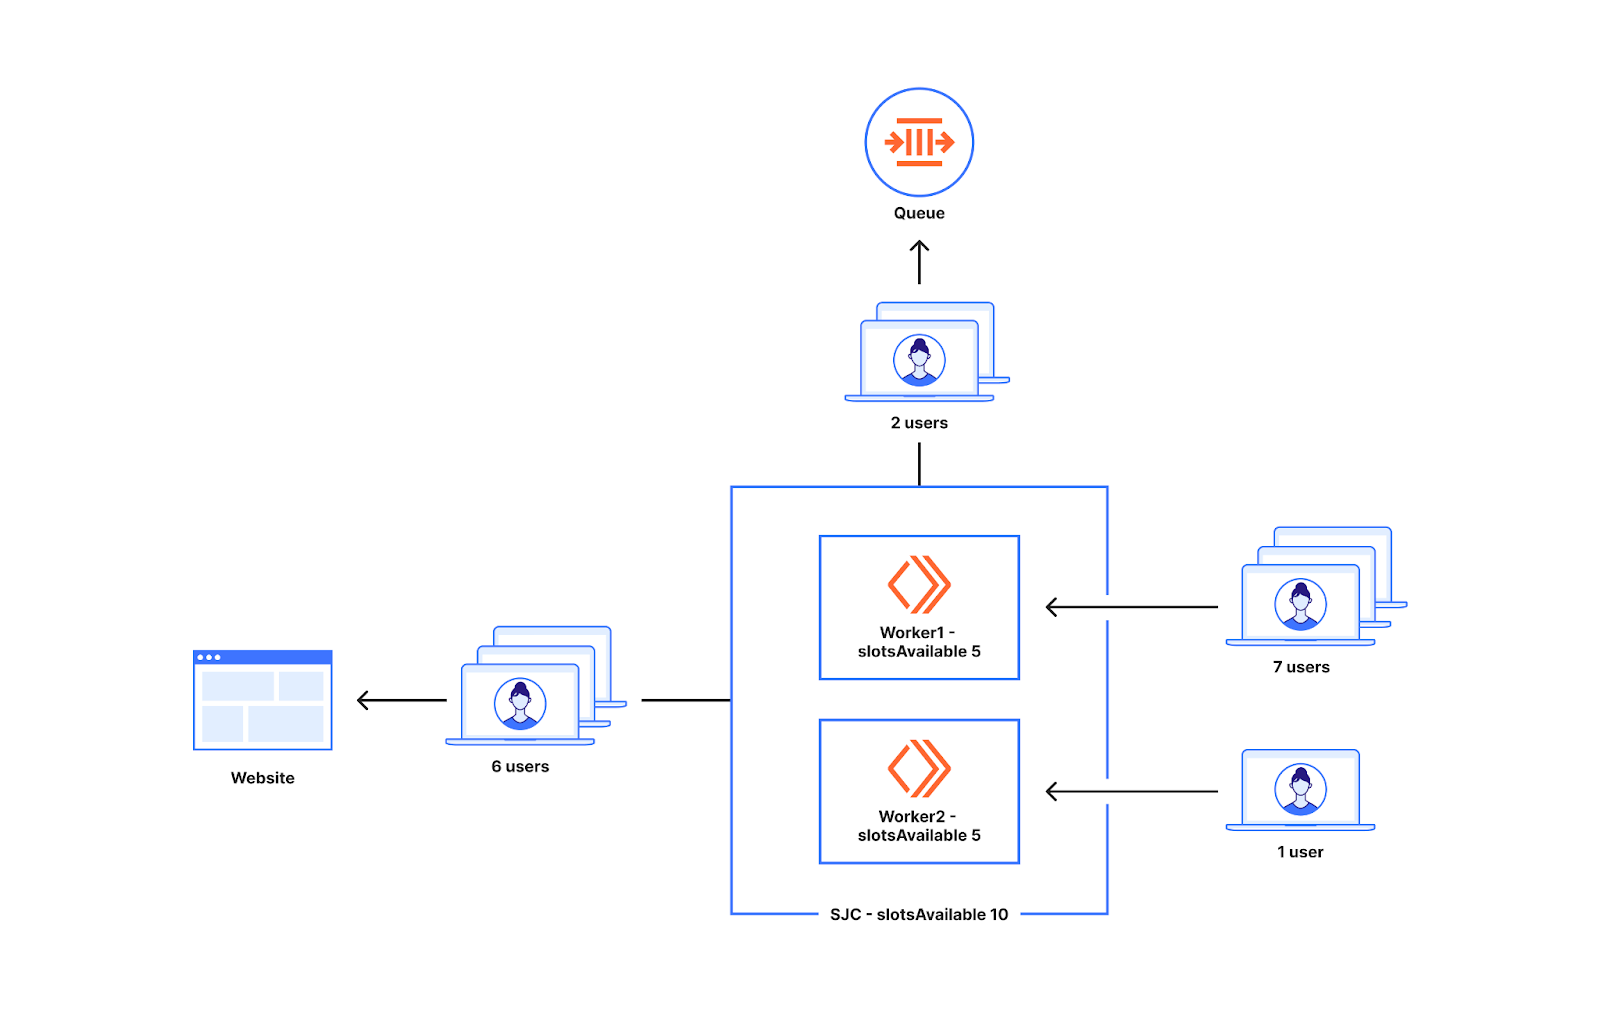
So the state indicates that there is space for the new users as there are only 50 active users when it's possible to have 200. So there is space for another 150 users to go in. Let's assume those 50 users could have come from two data centers San Jose (20 users) and London (30 users). We also keep track of the number of workers that are active across the globe as well as the number of workers active at the data center in which the state is calculated. The state key below could be the one calculated at San Jose.

{  
  "activeUsers": 50,
  "globalWorkersActive": 10,
  "dataCenterWorkersActive": 3,
  "trafficHistory": {
    "Mon, 11 Sep 2023 11:44:00 GMT": {
       San Jose: 20/200, // 10%
       London: 30/200, // 15%
       Anywhere: 150/200 // 75%
    }
  }
}

Imagine at the time "Mon, 11 Sep 2023 11:45:54 GMT", we get a request to that waiting room at a datacenter in San Jose.

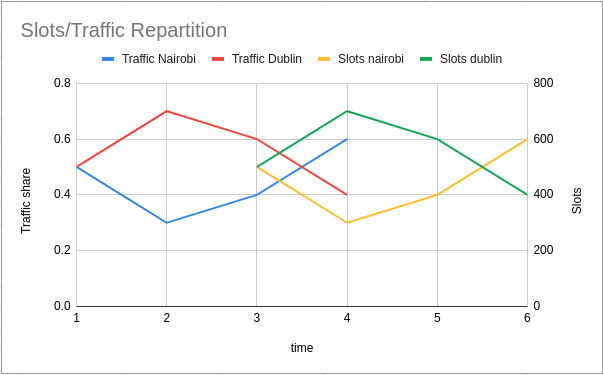
To see if the user that reached San Jose can go to the origin we first check the traffic history in the past minute to see the distribution of traffic at that time. This is because a lot of websites are popular in certain parts of the world. For a lot of these websites the traffic tends to come from the same data centers.

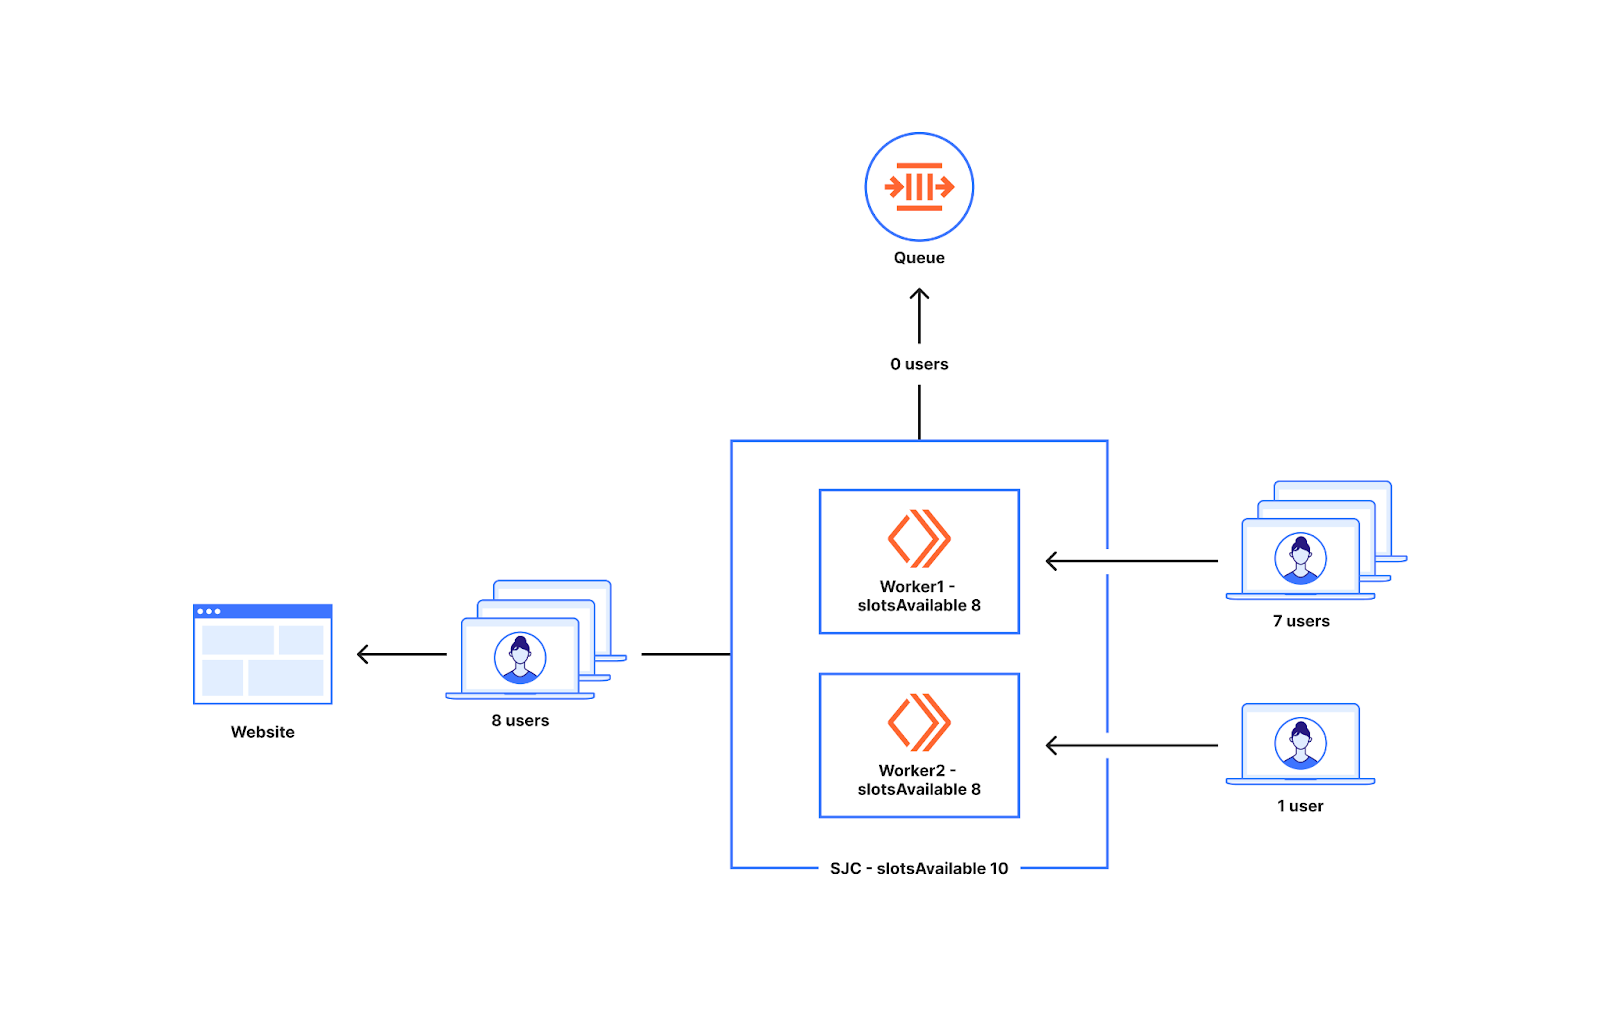
Looking at the traffic history for the minute "Mon, 11 Sep 2023 11:44:00 GMT" we see San Jose has 20 users out of 200 users going there (10%) at that time. For the current time "Mon, 11 Sep 2023 11:45:54 GMT" we divide the slots available at the website at the same ratio as the traffic history in the past minute. So we can send 10% of 150 slots available from San Jose which is 15 users. We also know that there are three active workers as "dataCenterWorkersActive" is 3.

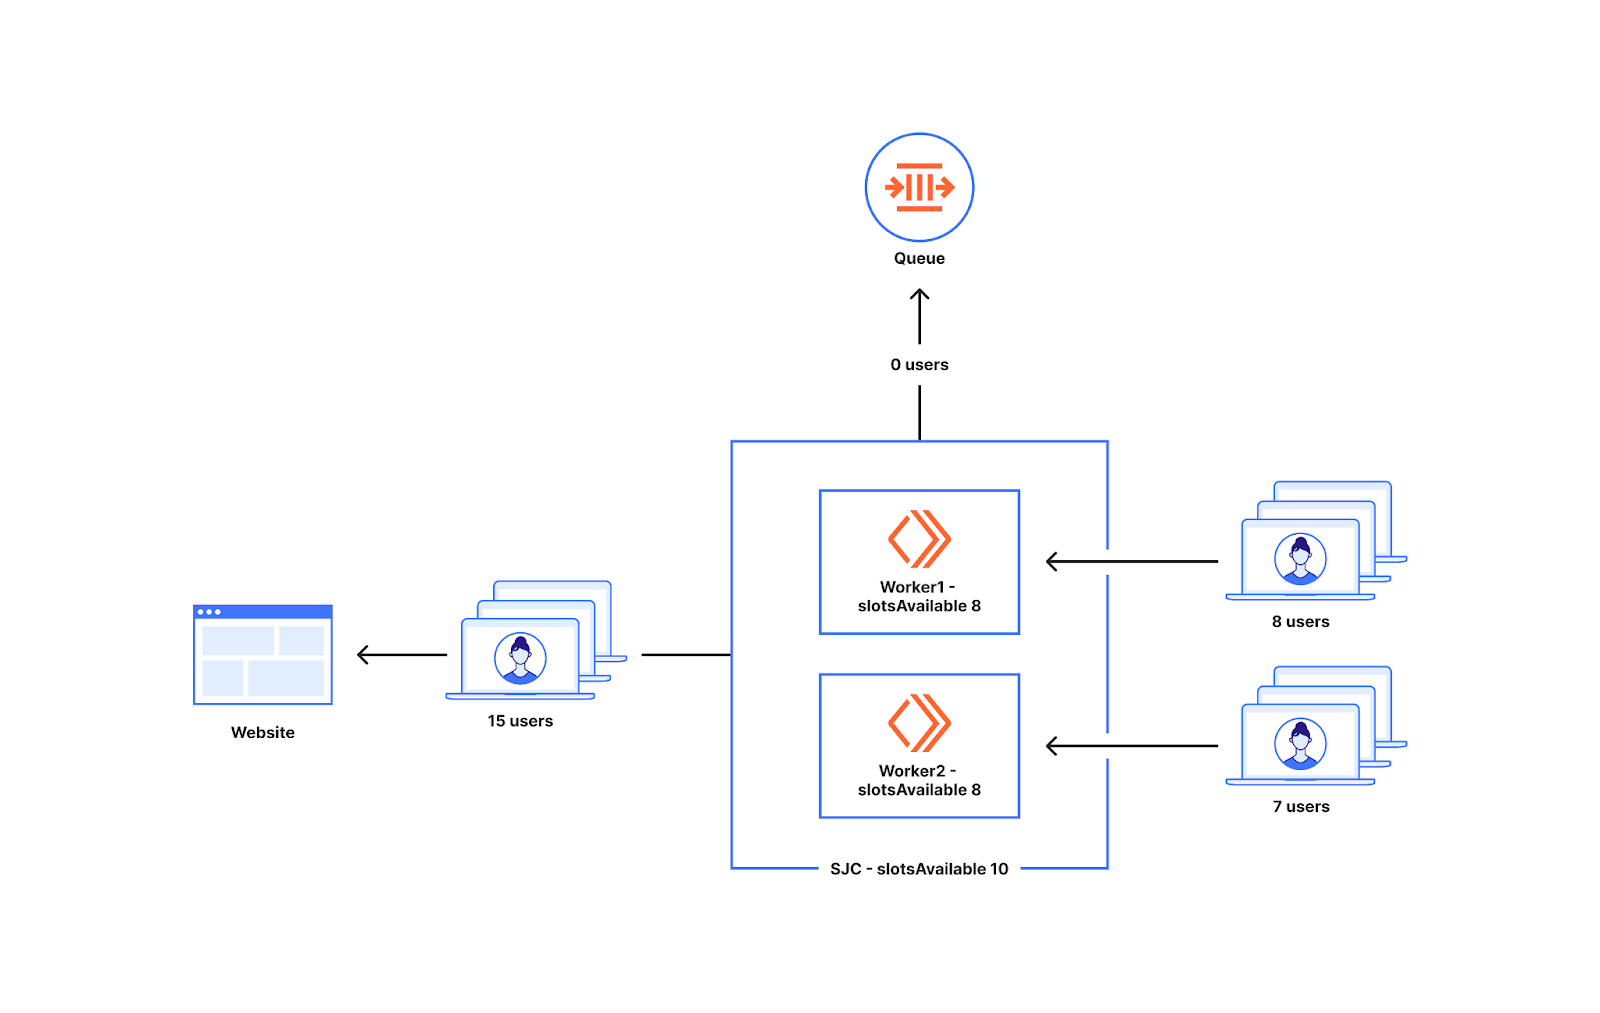
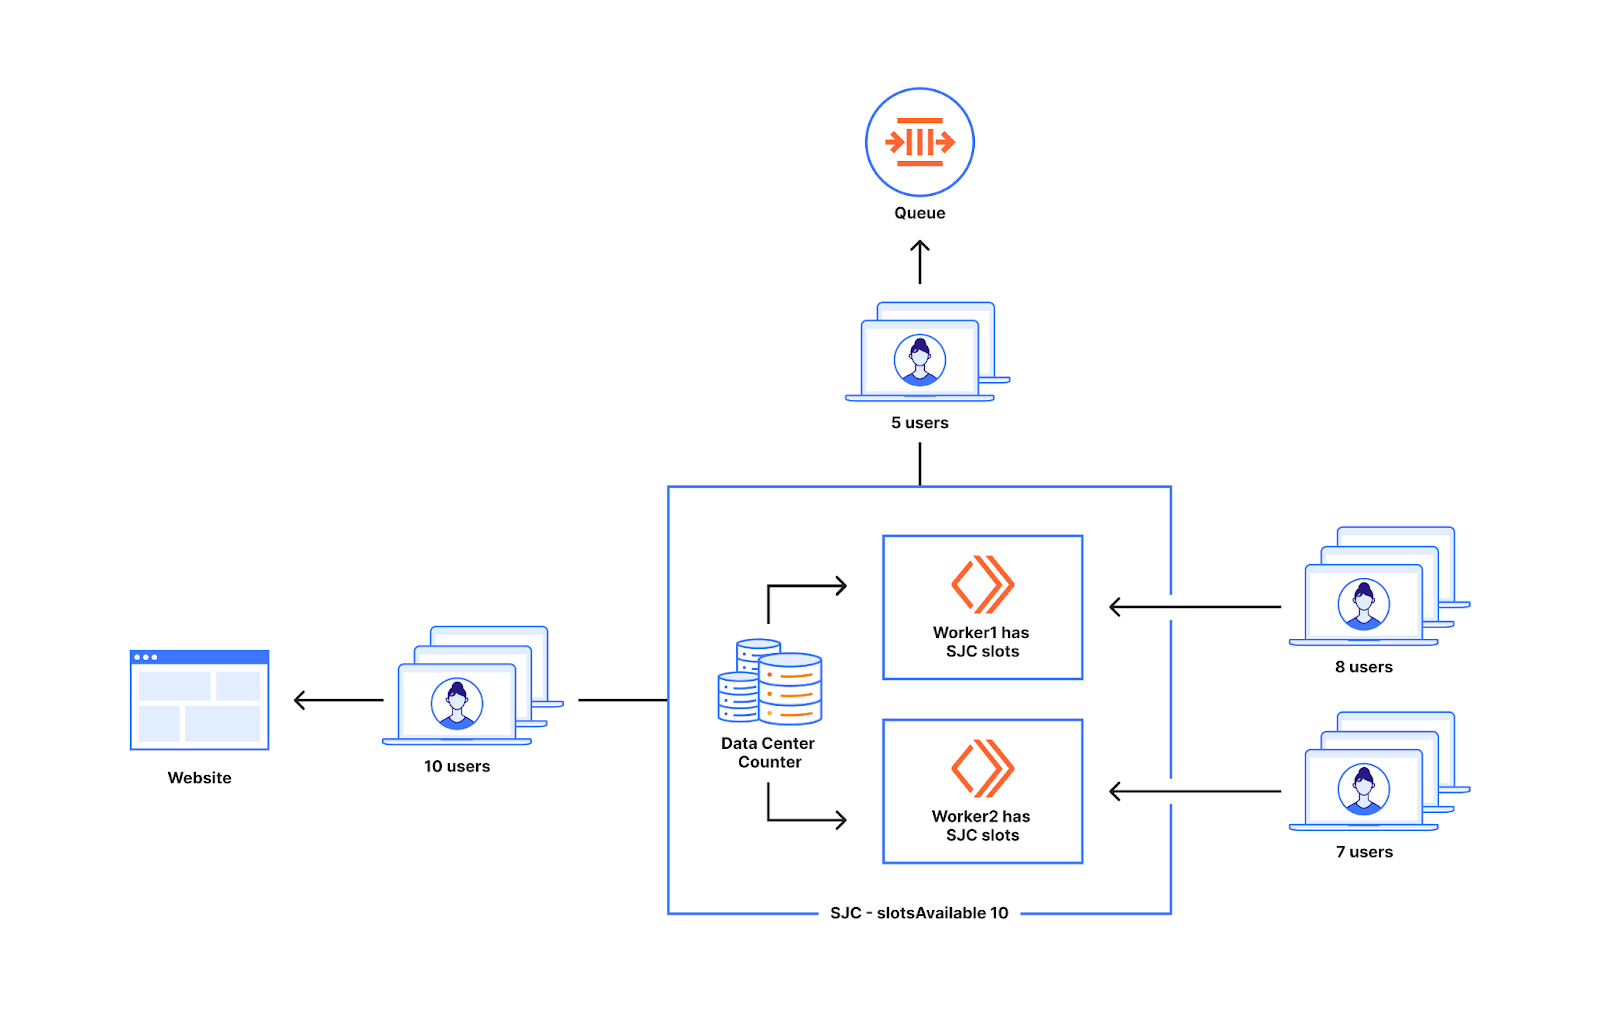
The number of slots available for the data center is divided evenly among the workers in the data center. So every worker in San Jose can send 15/3 users to the website. If the worker that received the traffic has not sent any users to the origin for the current minute they can send up to five users (15/3).

At the same time ("Mon, 11 Sep 2023 11:45:54 GMT"), imagine a request goes to a data center in Delhi. The worker at the data center in Delhi checks the trafficHistory and sees that there are no slots allotted for it. For traffic like this we have reserved the Anywhere slots as we are really far away from the limit.

{  
  "activeUsers":50,
  "globalWorkersActive": 10,
  "dataCenterWorkersActive": 1,
  "trafficHistory": {
    "Mon, 11 Sep 2023 11:44:00 GMT": {
       San Jose: 20/200, // 10%
       London: 30/200, // 15%
       Anywhere: 150/200 // 75%
    }
  }
}

The Anywhere slots are divided among all the active workers in the globe as any worker around the world can take a part of this pie. 75% of the remaining 150 slots which is 113.

The state key also keeps track of the number of workers (globalWorkersActive) that have spawned around the world. The Anywhere slots allotted are divided among all the active workers in the world if available. globalWorkersActive is 10 when we look at the waiting room state. So every active worker can send as many as 113/10 which is approximately 11 users. So the first 11 users that come to a worker in the minute Mon, 11 Sep 2023 11:45:00 GMT gets admitted to the origin. The extra users get queued. The extra reserved slots (5) in San Jose for minute  Mon, 11 Sep 2023 11:45:00 GMT discussed before ensures that we can admit up to 16(5 + 11) users from a worker from San Jose to the website.

Queuing at the worker level can cause users to get queued before the slots available for the data center

As we can see from the example above, we decide whether to queue or not at the worker level. The number of new users that go to workers around the world can be non-uniform. To understand what can happen when there is non-uniform distribution of traffic to two workers, let us look at the diagram below.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

Imagine the slots available for a data center in San Jose are ten. There are two workers running in San Jose. Seven users go to worker1 and one user goes to worker2. In this situation worker1 will let in five out of the seven workers to the website and two of them get queued as worker1 only has five slots available. The one user that shows up at worker2 also gets to go to the origin. So we queue two users, when in reality ten users can get sent from the datacenter San Jose when only eight users show up.

This issue while dividing slots evenly among workers results in queueing before a waiting room’s configured traffic limits, typically within 20-30% of the limits set. This approach has advantages which we will discuss next. We have made changes to the approach to decrease the frequency with which queuing occurs outside that 20-30% range, queuing as close to limits as possible, while still ensuring Waiting Room is prepared to catch spikes. Later in this blog, we will cover how we achieved this by updating how we allocate and count slots.

What is the advantage of workers making these decisions?

The example above talked about how a worker in San Jose and Delhi makes decisions to let users through to the origin. The advantage of making decisions at the worker level is that we can make decisions without any significant latency added to the request. This is because to make the decision, there is no need to leave the data center to get information about the waiting room as we are always working with the state that is currently available in the data center. The queueing starts when the slots run out within the worker. The lack of additional latency added enables the customers to turn on the waiting room all the time without worrying about extra latency to their users.

Waiting Room’s number one priority is to ensure that customer’s sites remain up and running at all times, even in the face of unexpected and overwhelming traffic surges. To that end, it is critical that a waiting room prioritizes staying near or below traffic limits set by the customer for that room. When a spike happens at one data center around the world, say at San Jose, the local state at the data center will take a few seconds to get to Delhi.

Splitting the slots among workers ensures that working with slightly outdated data does not cause the overall limit to be exceeded by an impactful amount. For example, the activeUsers value can be 26 in the San Jose data center and 100 in the other data center where the spike is happening. At that point in time, sending extra users from Delhi may not overshoot the overall limit by much as they only have a part of the pie to start with in Delhi. Therefore, queueing before overall limits are reached is part of the design to make sure your overall limits are respected. In the next section we will cover the approaches we implemented to queue as close to limits as possible without increasing the risk of exceeding traffic limits.

Allocating more slots when traffic is low relative to waiting room limits

The first case we wanted to address was queuing that occurs when traffic is far from limits. While rare and typically lasting for one refresh interval (20s) for the end users who are queued, this was our first priority when updating our queuing algorithm. To solve this, while allocating slots we looked at the utilization (how far you are from traffic limits) and allotted more slots when traffic is really far away from the limits. The idea behind this was to prevent the queueing that happens at lower limits while still being able to readjust slots available per worker when there are more users on the origin.

To understand this let's revisit the example where there is non-uniform distribution of traffic to two workers. So two workers similar to the one we discussed before are shown below. In this case the utilization is low (10%). This means we are far from the limits. So the slots allocated(8) are closer to the slotsAvailable for the datacenter San Jose which is 10. As you can see in the diagram below, all the eight users that go to either worker get to reach the website with this modified slot allocation as we are providing more slots per worker at lower utilization levels.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

The diagram below shows how the slots allocated per worker changes with utilization (how far you are away from limits). As you can see here, we are allocating more slots per worker at lower utilization. As the utilization increases, the slots allocated per worker decrease as it’s getting closer to the limits, and we are better prepared for spikes in traffic. At 10% utilization every worker gets close to the slots available for the data center. As the utilization is close to 100% it becomes close to the slots available divided by worker count in the data center.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

How do we achieve more slots at lower utilization?

This section delves into the mathematics which helps us get there. If you are not interested in these details, meet us at the “Risk of over provisioning” section.

To understand this further, let's revisit the previous example where requests come to the Delhi data center. The activeUsers value is 50, so utilization is 50/200 which is around 25%.

{
  "activeUsers": 50,
  "globalWorkersActive": 10,
  "dataCenterWorkersActive": 1,
  "trafficHistory": {
    "Mon, 11 Sep 2023 11:44:00 GMT": {
       San Jose: 20/200, // 10%
       London: 30/200, // 15%
       Anywhere: 150/200 // 75%
    }
  }
}

The idea is to allocate more slots at lower utilization levels. This ensures that customers do not see unexpected queueing behaviors when traffic is far away from limits. At time Mon, 11 Sep 2023 11:45:54 GMT requests to Delhi are at 25% utilization based on the local state key.

To allocate more slots to be available at lower utilization we added a workerMultiplier which moves proportionally to the utilization. At lower utilization the multiplier is lower and at higher utilization it is close to one.

workerMultiplier = (utilization)^curveFactor
adaptedWorkerCount = actualWorkerCount * workerMultiplier

utilization – how far away from the limits you are.

curveFactor – is the exponent which can be adjusted which decides how aggressive we are with the distribution of extra budgets at lower worker counts. To understand this let's look at the graph of how y = x and y = x^2 looks between values 0 and 1.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

The graph for y=x is a straight line passing through (0, 0) and (1, 1).

The graph for y=x^2 is a curved line where y increases slower than x when x < 1 and passes through (0, 0) and (1, 1)

Using the concept of how the curves work, we derived the formula for workerCountMultiplier where y=workerCountMultiplier, x=utilization and curveFactor is the power which can be adjusted which decides how aggressive we are with the distribution of extra budgets at lower worker counts. When curveFactor is 1, the workerMultiplier is equal to the utilization.

Let's come back to the example we discussed before and see what the value of the curve factor will be. At time Mon, 11 Sep 2023 11:45:54 GMT requests to Delhi are at 25% utilization based on the local state key. The Anywhere slots are divided among all the active workers in the globe as any worker around the world can take a part of this pie. i.e. 75% of the remaining 150 slots (113).

globalWorkersActive is 10 when we look at the waiting room state. In this case we do not divide the 113 slots by 10 but instead divide by the adapted worker count which is globalWorkersActive * workerMultiplier. If curveFactor is 1, the workerMultiplier is equal to the utilization which is at 25% or 0.25.

So effective workerCount = 10 * 0.25 = 2.5

So, every active worker can send as many as 113/2.5 which is approximately 45 users. The first 45 users that come to a worker in the minute Mon, 11 Sep 2023 11:45:00 GMT gets admitted to the origin. The extra users get queued.

Therefore, at lower utilization (when traffic is farther from the limits) each worker gets more slots. But, if the sum of slots are added up, there is a higher chance of exceeding the overall limit.

Risk of over provisioning

The method of giving more slots at lower limits decreases the chances of queuing when traffic is low relative to traffic limits. However, at lower utilization levels a uniform spike happening around the world could cause more users to go into the origin than expected. The diagram below shows the case where this can be an issue. As you can see the slots available are ten for the data center. At 10% utilization we discussed before, each worker can have eight slots each. If eight users show up at one worker and seven show up at another, we will be sending fifteen users to the website when only ten are the maximum available slots for the data center.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

With the range of customers and types of traffic we have, we were able to see cases where this became a problem. A traffic spike from low utilization levels could cause overshooting of the global limits. This is because we are over provisioned at lower limits and this increases the risk of significantly exceeding traffic limits. We needed to implement a safer approach which would not cause limits to be exceeded while also decreasing the chance of queueing when traffic is low relative to traffic limits.

Taking a step back and thinking about our approach, one of the assumptions we had was that the traffic in a data center directly correlates to the worker count that is found in a data center. In practice what we found is that this was not true for all customers. Even if the traffic correlates to the worker count, the new users going to the workers in the data centers may not correlate. This is because the slots we allocate are for new users but the traffic that a data center sees consists of both users who are already on the website and new users trying to go to the website.

In the next section we are talking about an approach where worker counts do not get used and instead workers communicate with other workers in the data center. For that we introduced a new service which is a durable object counter.

Decrease the number of times we divide the slots by introducing Data Center Counters

From the example above, we can see that overprovisioning at the worker level has the risk of using up more slots than what is allotted for a data center. If we do not over provision at low levels we have the risk of queuing users way before their configured limits are reached which we discussed first. So there has to be a solution which can achieve both these things.

The overprovisioning was done so that the workers do not run out of slots quickly when an uneven number of new users reach a bunch of workers. If there is a way to communicate between two workers in a data center, we do not need to divide slots among workers in the data center based on worker count. For that communication to take place, we introduced counters. Counters are a bunch of small durable object instances that do counting for a set of workers in the data center.

To understand how it helps with avoiding usage of worker counts, let's check the diagram below. There are two workers talking to a Data Center Counter below. Just as we discussed before, the workers let users through to the website based on the waiting room state. The count of the number of users let through was stored in the memory of the worker before. By introducing counters, it is done in the Data Center Counter. Whenever a new user makes a request to the worker, the worker talks to the counter to know the current value of the counter. In the example below for the first new request to the worker the counter value received is 9. When a data center has 10 slots available, that will mean the user can go to the website. If the next worker receives a new user and makes a request just after that, it will get a value 10 and based on the slots available for the worker, the user will get queued.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

The Data Center Counter acts as a point of synchronization for the workers in the waiting room. Essentially, this enables the workers to talk to each other without really talking to each other directly. This is similar to how a ticketing counter works. Whenever one worker lets someone in, they request tickets from the counter, so another worker requesting the tickets from the counter will not get the same ticket number. If the ticket value is valid, the new user gets to go to the website. So when different numbers of new users show up at workers, we will not over allocate or under allocate slots for the worker as the number of slots used is calculated by the counter which is for the data center.

The diagram below shows the behavior when an uneven number of new users reach the workers, one gets seven new users and the other worker gets one new user. All eight users that show up at the workers in the diagram below get to the website as the slots available for the data center is ten which is below ten.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

This also does not cause excess users to get sent to the website as we do not send extra users when the counter value equals the slotsAvailable for the data center. Out of the fifteen users that show up at the workers in the diagram below ten will get to the website and five will get queued which is what we would expect.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

Risk of over provisioning at lower utilization also does not exist as counters help workers to communicate with each other.

To understand this further, let's look at the previous example we talked about and see how it works with the actual waiting room state.

The waiting room state for the customer is as follows.

{  
  "activeUsers": 50,
  "globalWorkersActive": 10,
  "dataCenterWorkersActive": 3,
  "trafficHistory": {
    "Mon, 11 Sep 2023 11:44:00 GMT": {
       San Jose: 20/200, // 10%
       London: 30/200, // 15%
       Anywhere: 150/200 // 75%
    }
  }
}

The objective is to not divide the slots among workers so that we don’t need to use that information from the state. At time Mon, 11 Sep 2023 11:45:54 GMT requests come to San Jose. So, we can send 10% of 150 slots available from San Jose which is 15.

The durable object counter at San Jose keeps returning the counter value it is at right now for every new user that reaches the data center. It will increment the value by 1 after it returns to a worker. So the first 15 new users that come to the worker get a unique counter value. If the value received for a user is less than 15 they get to use the slots at the data center.

Once the slots available for the data center runs out, the users can make use of the slots allocated for Anywhere data-centers as these are not reserved for any particular data center. Once a worker in San Jose gets a ticket value that says 15, it realizes that it's not possible to go to the website using the slots from San Jose.

The Anywhere slots are available for all the active workers in the globe i.e. 75% of the remaining 150 slots (113). The Anywhere slots are handled by a durable object that workers from different data centers can talk to when they want to use Anywhere slots. Even if 128 (113 + 15) users end up going to the same worker for this customer we will not queue them. This increases the ability of Waiting Room to handle an uneven number of new users going to workers around the world which in turn helps the customers to queue close to the configured limits.

Why do counters work well for us?

When we built the Waiting Room, we wanted the decisions for entry into the website to be made at the worker level itself without talking to other services when the request is in flight to the website. We made that choice to avoid adding latency to user requests. By introducing a synchronization point at a durable object counter, we are deviating from that by introducing a call to a durable object counter.

However, the durable object for the data center stays within the same data center. This leads to minimal additional latency which is usually less than 10 ms. For the calls to the durable object that handles Anywhere data centers, the worker may have to cross oceans and long distances. This could cause the latency to be around 60 or 70 ms in those cases. The 95th percentile values shown below are higher because of calls that go to farther data centers.

How Waiting Room makes queueing decisions on Cloudflare's highly distributed network

The design decision to add counters adds a slight extra latency for new users going to the website. We deemed the trade-off acceptable because this reduces the number of users that get queued before limits are reached. In addition, the counters are only required when new users try to go into the website. Once new users get to the origin, they get entry directly from workers as the proof of entry is available in the cookies that the customers come with, and we can let them in based on that.

Counters are really simple services which do simple counting and do nothing else. This keeps the memory and CPU footprint of the counters minimal. Moreover, we have a lot of counters around the world handling the coordination between a subset of workers.This helps counters to successfully handle the load for the synchronization requirements from the workers. These factors add up to make counters a viable solution for our use case.

Summary

Waiting Room was designed with our number one priority in mind–to ensure that our customers’ sites remain up and running, no matter the volume or ramp up of legitimate traffic. Waiting Room runs on every server in Cloudflare’s network, which spans over 300 cities in more than 100 countries. We want to make sure, for every new user, the decision whether to go to the website or the queue is made with minimal latency and is done at the right time. This decision is a hard one as queuing too early at a data center can cause us to queue earlier than the customer set limits. Queuing too late can cause us to overshoot the customer set limits.

With our initial approach where we divide slots among our workers evenly we were sometimes queuing too early but were pretty good at respecting customer set limits. Our next approach of giving more slots at low utilization (low traffic levels compared to customer limits) ensured that we did better at the cases where we queued earlier than the customer set limits as every worker has more slots to work with at each worker. But as we have seen, this made us more likely to overshoot when a sudden spike in traffic occurred after a period of low utilization.

With counters we are able to get the best of both worlds as we avoid the division of slots by worker counts. Using counters we are able to ensure that we do not queue too early or too late based on the customer set limits. This comes at the cost of a little bit of latency to every request from a new user which we have found to be negligible and creates a better user experience than getting queued early.

We keep iterating on our approach to make sure we are always queuing people at the right time and above all protecting your website. As more and more customers are using the waiting room, we are learning more about different types of traffic and that is helping the product be better for everyone.

Building scheduling system with Workers and Durable Objects

Post Syndicated from Adam Janiš original https://blog.cloudflare.com/building-scheduling-system-with-workers-and-durable-objects/

Building scheduling system with Workers and Durable Objects

Building scheduling system with Workers and Durable Objects

We rely on technology to help us on a daily basis – if you are not good at keeping track of time, your calendar can remind you when it’s time to prepare for your next meeting. If you made a reservation at a really nice restaurant, you don’t want to miss it! You appreciate the app to remind you a day before your plans the next evening.

However, who tells the application when it’s the right time to send you a notification? For this, we generally rely on scheduled events. And when you are relying on them, you really want to make sure that they occur. Turns out, this can get difficult. The scheduler and storage backend need to be designed with scale in mind – otherwise you may hit limitations quickly.

Workers, Durable Objects, and Alarms are actually a perfect match for this type of workload. Thanks to the distributed architecture of Durable Objects and their storage, they are a reliable and scalable option. Each Durable Object has access to its own isolated storage and alarm scheduler, both being automatically replicated and failover in case of failures.

There are many use cases where having a reliable scheduler can come in handy: running a webhook service, sending emails to your customers a week after they sign up to keep them engaged, sending invoices reminders, and more!

Today, we’re going to show you how to build a scalable service that will schedule HTTP requests on a specific schedule or as one-off at a specific time as a way to guide you through any use case that requires scheduled events.

Building scheduling system with Workers and Durable Objects

Quick intro into the application stack

Before we dive in, here are some of the tools we’re going to be using today:

The application is going to have following components:

  • Scheduling system API to accept scheduled requests and manage Durable Objects
  • Unique Durable Object per scheduled request, each with
  • Storage – keeping the request metadata, such as URL, body, or headers.
  • Alarm – a timer (trigger) to wake Durable Object up.

While we will focus on building the application, the Cloudflare global network will take care of the rest – storing and replicating our data, and making sure to wake our Durable Objects up when the time’s right. Let’s build it!

Initialize new Workers project

Get started by generating a completely new Workers project using the wrangler init command, which makes creating new projects quick & easy.

wrangler init -y durable-objects-requests-scheduler

Building scheduling system with Workers and Durable Objects

For more information on how to install, authenticate, or update Wrangler, check out https://developers.cloudflare.com/workers/wrangler/get-started

Preparing TypeScript types

From my personal experience, at least a draft of TypeScript types significantly helps to be more productive down the road, so let’s prepare and describe our scheduled request in advance. Create a file types.ts in src directory and paste the following TypeScript definitions.

src/types.ts

export interface Env {
    DO_REQUEST: DurableObjectNamespace
}
 
export interface ScheduledRequest {
  url: string // URL of the request
  triggerAt?: number // optional, unix timestamp in milliseconds, defaults to `new Date()`
  requestInit?: RequestInit // optional, includes method, headers, body
}

A scheduled request Durable Object class & alarm

Based on our architecture design, each scheduled request will be saved into its own Durable Object, effectively separating storage and alarms from each other and allowing our scheduling system to scale horizontally – there is no limit to the number of Durable Objects we create.

In the end, the Durable Object class is a matter of a couple of lines. The code snippet below accepts and saves the request body to a persistent storage and sets the alarm timer. Workers runtime will wake up the Durable Object and call the alarm() method to process the request.

The alarm method reads the scheduled request data from the storage, then processes the request, and in the end reschedules itself in case it’s configured to be executed on a recurring schedule.

src/request-durable-object.ts

import { ScheduledRequest } from "./types";
 
export class RequestDurableObject {
  id: string|DurableObjectId
  storage: DurableObjectStorage
 
  constructor(state:DurableObjectState) {
    this.storage = state.storage
    this.id = state.id
  }
 
    async fetch(request:Request) {
    // read scheduled request from request body
    const scheduledRequest:ScheduledRequest = await request.json()
     
    // save scheduled request data to Durable Object storage, set the alarm, and return Durable Object id
    this.storage.put("request", scheduledRequest)
    this.storage.setAlarm(scheduledRequest.triggerAt || new Date())
    return new Response(JSON.stringify({
      id: this.id.toString()
    }), {
      headers: {
        "content-type": "application/json"
      }
    })
  }
 
  async alarm() {
    // read the scheduled request from Durable Object storage
    const scheduledRequest:ScheduledRequest|undefined = await this.storage.get("request")
 
    // call fetch on scheduled request URL with optional requestInit
    if (scheduledRequest) {
      await fetch(scheduledRequest.url, scheduledRequest.requestInit ? webhook.requestInit : undefined)
 
      // cleanup scheduled request once done
      this.storage.deleteAll()
    }
  }
}

Wrangler configuration

Once we have the Durable Object class, we need to create a Durable Object binding by instructing Wrangler where to find it and what the exported class name is.

wrangler.toml

name = "durable-objects-request-scheduler"
main = "src/index.ts"
compatibility_date = "2022-08-02"
 
# added Durable Objects configuration
[durable_objects]
bindings = [
  { name = "DO_REQUEST", class_name = "RequestDurableObject" },
]
 
[[migrations]]
tag = "v1"
new_classes = ["RequestDurableObject"]

Scheduling system API

The API Worker will accept POST HTTP methods only, and is expecting a JSON body with scheduled request data – what URL to call, optionally what method, headers, or body to send. Any other method than POST will return 405 – Method Not Allowed HTTP error.

HTTP POST /:scheduledRequestId? will create or override a scheduled request, where :scheduledRequestId is optional Durable Object ID returned from a scheduling system API before.

src/index.ts

import { Env } from "./types"
export { RequestDurableObject } from "./request-durable-object"
 
export default {
    async fetch(
        request: Request,
        env: Env
    ): Promise<Response> {
        if (request.method !== "POST") {
            return new Response("Method Not Allowed", {status: 405})
        }
 
        // parse the URL and get Durable Object ID from the URL
        const url = new URL(request.url)
        const idFromUrl = url.pathname.slice(1)
 
        // construct the Durable Object ID, use the ID from pathname or create a new unique id
        const doId = idFromUrl ? env.DO_REQUEST.idFromString(idFromUrl) : env.DO_REQUEST.newUniqueId()
 
        // get the Durable Object stub for our Durable Object instance
        const stub = env.DO_REQUEST.get(doId)
 
        // pass the request to Durable Object instance
        return stub.fetch(request)
    },
}

It’s good to mention that the script above does not implement any listing of scheduled or processed webhooks. Depending on how the scheduling system would be integrated, you can save each created Durable Object ID to your existing backend, or write your own registry – using one of the Workers storage options.

Starting a local development server and testing our application

We are almost done! Before we publish our scheduler system to the Cloudflare edge, let’s start Wrangler in a completely local mode to run a couple of tests against it and to see it in action – which will work even without an Internet connection!

wrangler dev --local
Building scheduling system with Workers and Durable Objects

The development server is listening on localhost:8787, which we will use for scheduling our first request. The JSON request payload should match the TypeScript schema we defined in the beginning – required URL, and optional triggerEverySeconds number or triggerAt unix timestamp. When only the required URL is passed, the request will be dispatched right away.

An example of request payload that will send a GET request to https://example.com every 30 seconds.

{
	"url":  "https://example.com",
	"triggerEverySeconds": 30,
}
> curl -X POST -d '{"url": "https://example.com", "triggerEverySeconds": 30}' http://localhost:8787
{"id":"000000018265a5ecaa5d3c0ab6a6997bf5638fdcb1a8364b269bd2169f022b0f"}
Building scheduling system with Workers and Durable Objects

From the wrangler logs we can see the scheduled request ID 000000018265a5ecaa5d3c0ab6a6997bf5638fdcb1a8364b269bd2169f022b0f is being triggered in 30s intervals.

Need to double the interval? No problem, just send a new POST request and pass the request ID as a pathname.

> curl -X POST -d '{"url": "https://example.com", "triggerEverySeconds": 60}' http://localhost:8787/000000018265a5ecaa5d3c0ab6a6997bf5638fdcb1a8364b269bd2169f022b0f
{"id":"000000018265a5ecaa5d3c0ab6a6997bf5638fdcb1a8364b269bd2169f022b0f"}

Every scheduled request gets a unique Durable Object ID with its own storage and alarm. As we demonstrated, the ID becomes handy when you need to change the settings of the scheduled request, or to deschedule them completely.

Publishing to the network

Following command will bundle our Workers application, export and bind Durable Objects, and deploy it to our workers.dev subdomain.

wrangler publish
Building scheduling system with Workers and Durable Objects

That’s it, we are live! 🎉 The URL of your deployment is shown in the Workers logs. In a reasonably short period of time we managed to write our own scheduling system that is ready to handle requests at scale.

You can check full source code in Workers templates repository, or experiment from your browser without installing any dependencies locally using the StackBlitz template.

What to see or build next

Announcing our Spring Developer Challenge

Post Syndicated from Albert Zhao original https://blog.cloudflare.com/announcing-our-spring-developer-challenge/

Announcing our Spring Developer Challenge

Announcing our Spring Developer Challenge

After many announcements from Platform Week, we’re thrilled to make one more: our Spring Developer Challenge!

The theme for this challenge is building real-time, collaborative applications — one of the most exciting use-cases emerging in the Cloudflare ecosystem. This is an opportunity for developers to merge their ideas with our newly released features, earn recognition on our blog, and take home our best swag yet.

Here’s a list of our tools that will get you started:

  • Workers can either be powerful middleware connecting your app to different APIs and an origin — or it can be the entire application itself. We recommend using Worktop, a popular framework for Workers, if you need TypeScript support, routing, and well-organized submodules. Worktop can also complement your existing app even if it already uses a framework,  such as Svelte.
  • Cloudflare Pages makes it incredibly easy to deploy sites, which you can make into truly dynamic apps by putting a Worker in front or using the Pages Functions (beta).
  • Durable Objects are great for collaborative apps because you can use websockets while coordinating state at the edge, seen in this chat demo. To help scale any load, we also recommend Durable Object Groups.
  • Workers KV provides a global key-value data store that securely stores and quickly serves data across Cloudflare’s network. R2 allows you to store enormous amounts of data without trapping you with costly egress services.

Last year, our Developer Spotlight series highlighted how developers around the world built entire applications on Cloudflare. Our Discord server maintained that momentum with users demonstrating that any type of application can be built. Need a way to organize thousands of lines of JSON? JSON Hero, built with Remix and deployed with Workers, provides an incredibly readable UI for your JSON files. Trying to deploy a GraphQL server for your app that scales? helix-flare deploys a GraphQL server easily through Workers and uses Durable Objects to coordinate data.

We hope developers continue to explore the boundaries of what they can build on Cloudflare as our platform evolves. During our Summer Developer Challenge in 2021, we received over 1,200 submissions that revealed you can build almost any app imaginable with Workers, Pages, and the rest of the developer ecosystem. We sent out hundreds of swag boxes to participants, to show our appreciation. The ensuing unboxing videos on Twitter and YouTube thrilled our team.

This year’s Spring Developer Challenge is all about making real-time, collaborative apps such as chat rooms, games, web-based editing tools, or anything else in your imagination! Here are the rules:

  • You must be at least 18 years old to participate
  • You can work in teams of up to 10 people per submission
  • The deadline to submit your repo is May 24

Enter the challenge by going to this site.

As you build your app, join our Discord if you or your team need any help. We will be enthusiastically reviewing submissions, promoting them on Twitter, and sending out swag boxes.

If you’re new to Cloudflare or have an exciting idea as a developer, this is your opportunity to see how far our platform has evolved and get rewarded for it!

Durable Objects Alarms — a wake-up call for your applications

Post Syndicated from Matt Alonso original https://blog.cloudflare.com/durable-objects-alarms/

Durable Objects Alarms — a wake-up call for your applications

Durable Objects Alarms — a wake-up call for your applications

Since we launched Durable Objects, developers have leveraged them as a novel building block for distributed applications.

Durable Objects provide globally unique instances of a JavaScript class a developer writes, accessed via a unique ID. The Durable Object associated with each ID implements some fundamental component of an application — a banking application might have a Durable Object representing each bank account, for example. The bank account object would then expose methods for incrementing a balance, transferring money or any other actions that the application needs to do on the bank account.

Durable Objects work well as a stateful backend for applications — while Workers can instantiate a new instance of your code in any of Cloudflare’s data centers in response to a request, Durable Objects guarantee that all requests for a given Durable Object will reach the same instance on Cloudflare’s network.

Each Durable Object is single-threaded and has access to a stateful storage API, making it easy to build consistent and highly-available distributed applications on top of them.

This system makes distributed systems’ development easier — we’ve seen some impressive applications launched atop Durable Objects, from collaborative whiteboarding tools to conflict-free replicated data type (CRDT) systems for coordinating distributed state launch.

However, up until now, there’s been a piece missing — how do you invoke a Durable Object when a client Worker is not making requests to it?

As with any distributed system, Durable Objects can become unavailable and stop running. Perhaps the machine you were running on was unplugged, or the datacenter burned down and is never coming back, or an individual object exceeded its memory limit and was reset. Before today, a subsequent request would reinitialize the Durable Object on another machine, but there was no way to programmatically wake up an Object.

Durable Objects Alarms are here to change that, unlocking new use cases for Durable Objects like queues and deferred processing.

What is a Durable Object Alarm?

Durable Object Alarms allow you, from within your Durable Object, to schedule the object to be woken up at a time in the future. When the alarm’s scheduled time comes, the Durable Object’s alarm() handler will be called. If this handler throws an exception, the alarm will be automatically retried using exponential backoff until it succeeds — alarms have guaranteed at-least-once execution.

How are Alarms different from Workers Cron Triggers?

Alarms are more fine-grained than Cron Triggers. While a Workers service can have up to three Cron Triggers configured at once, it can have an unlimited amount of Durable Objects, each of which can have a single alarm active at a time.

Alarms are directly scheduled from and invoke a function within your Durable Object. Cron Triggers, on the other hand, are not programmatic — they execute based on their schedules, which have to be configured via the Cloudflare Dashboard or centralized configuration APIs.

How do I use Alarms?

First, you’ll need to add the durable_object_alarms compatibility flag to your wrangler.toml.

compatibility_flags = ["durable_object_alarms"]

Next, implement an alarm() handler in your Durable Object that will be called when the alarm executes. From anywhere else in your Durable Object, call state.storage.setAlarm() and pass in a time for the alarm to run at. You can use state.storage.getAlarm() to retrieve the currently set alarm time.

In this example, we implemented an alarm handler that wakes the Durable Object up once every 10 seconds to batch requests to a single Durable Object, deferring processing until there is enough work in the queue for it to be worthwhile to process them.

export default {
  async fetch(request, env) {
    let id = env.BATCHER.idFromName("foo");
    return await env.BATCHER.get(id).fetch(request);
  },
};

const SECONDS = 1000;

export class Batcher {
  constructor(state, env) {
    this.state = state;
    this.storage = state.storage;
    this.state.blockConcurrencyWhile(async () => {
      let vals = await this.storage.list({ reverse: true, limit: 1 });
      this.count = vals.size == 0 ? 0 : parseInt(vals.keys().next().value);
    });
  }
  async fetch(request) {
    this.count++;

    // If there is no alarm currently set, set one for 10 seconds from now
    // Any further POSTs in the next 10 seconds will be part of this kh.
    let currentAlarm = await this.storage.getAlarm();
    if (currentAlarm == null) {
      this.storage.setAlarm(Date.now() + 10 * SECONDS);
    }

    // Add the request to the batch.
    await this.storage.put(this.count, await request.text());
    return new Response(JSON.stringify({ queued: this.count }), {
      headers: {
        "content-type": "application/json;charset=UTF-8",
      },
    });
  }
  async alarm() {
    let vals = await this.storage.list();
    await fetch("http://example.com/some-upstream-service", {
      method: "POST",
      body: Array.from(vals.values()),
    });
    await this.storage.deleteAll();
    this.count = 0;
  }
}

Once every 10 seconds, the alarm() handler will be called. In the event an unexpected error terminates the Durable Object, it will be re-instantiated on another machine, following a short delay, after which it can continue processing.

Under the hood, Alarms are implemented by making reads and writes to the storage layer. This means Alarm get and set operations follow the same rules as any other storage operation – writes are coalesced with other writes, and reads have a defined ordering. See our blog post on the caching layer we implemented for Durable Objects for more information.

Durable Objects Alarms guarantee fault-tolerance

Alarms are designed to have no single point of failure and to run entirely on our edge – every Cloudflare data center running Durable Objects is capable of running alarms, including migrating Durable Objects from unhealthy data centers to healthy ones as necessary to ensure that their Alarm executes. Single failures should resolve in under 30 seconds, while multiple failures may take slightly longer.

We achieve this by storing alarms in the same distributed datastore that backs the Durable Object storage API. This allows alarm reads and writes to behave identically to storage reads and writes and to be performed atomically with them, and ensures that alarms are replicated across multiple datacenters.

Within each data center capable of running Durable Objects, there are multiple processes responsible for tracking upcoming alarms and triggering them, providing fault tolerance and scalability within the data center. A single elected leader in each data center is responsible for detecting failure of other data centers and assigning responsibility of those alarms to healthy local processes in its own data center. In the event of leader failure, another leader will be elected and become responsible for executing Alarms in the data center. This allows us to guarantee at-least-once execution for all Alarms.

How do I get started?

Alarms are a great way to build new distributed primitives, like queues, atop Durable Objects. They also provide a method for guaranteeing work within a Durable Object will complete, without relying on a client request to “kick” the Object.

You can get started with Alarms now by enabling Durable Objects in the Cloudflare dashboard. For more info, check the developer docs or jump in our Discord.

Developer Spotlight: Winning a Game Jam with Jamstack and Durable Objects

Post Syndicated from Erwin van der Koogh original https://blog.cloudflare.com/developer-spotlight-guido-zuidhof-full-tilt/

Developer Spotlight: Winning a Game Jam with Jamstack and Durable Objects

Developer Spotlight: Winning a Game Jam with Jamstack and Durable Objects

Welcome to a new blog post series called Developer Spotlight. In this series we will be showcasing interesting applications built on top of the Cloudflare Workers Ecosystem.

And to celebrate Durable Objects going GA, what better to kick off the series than with a really cool tech demo of Durable Objects called Full Tilt?

Full Tilt by Guido Zuidhof is a game jam entry for Ludum Dare, one of the biggest and oldest game jams around, where he won first place in the innovation category. A game jam is like a hackathon for games, where you have a very short amount of time (usually 48-72 hours) to create a game from scratch.

We love Full Tilt, not just because Guido used Workers and Durable Objects to build a cool game where you control a game on your computer via your phone, but especially because it shows how powerful Durable Objects are. In less than 48 hours Guido was able to write all the logic to instantly spin up a personal gaming server anywhere in the world, as close to that player as possible. And it is so fast that you feel like you are controlling the computer directly.

But here is Guido, to tell you about his experience developing Full Tilt.

Last October I participated in the Ludum Dare 49 game jam. The thing I love about game jams is that the time constraint forces you to work quickly, iterate often, and most importantly cut scope.

In this game jam I created Full Tilt, a game in which you seamlessly use your phone as a Wiimote-like motion controller for a game that is run on your laptop in a web browser. The secret sauce to making it so smooth was in combining a game jam with Jamstack and mixing in some Durable Objects.

You can try the game right here.

Phone as a controller

Full Tilt is a browser game in which you move the player character by moving your hand around. There are a few different ways we can do that. One idea would be to use your computer’s webcam to track a marker object through 3D space. While that is possible, it is tricky to get it working in any situation (a dark room can be problematic!) and also some players may feel uncomfortable turning on their webcam for a simple web game.

A smartphone has a bunch of sensors built in, including a magnetometer and gyroscope — those sensors are exactly what we need, and we can assume that the majority of our potential players have a smartphone within arm’s reach. When a native mobile application uses these sensors, it adds a lot of friction (users now have to install an app), as well as a bunch of implementation work. Fortunately modern web browsers allow you to read from these sensors through the DeviceMotion API: a small web app will do the job perfectly!

The next challenge is communicating the sensor readings from the phone to the game running on the main computer. For that we will use a combination of Cloudflare Workers and Durable Objects. There needs to be some shared contact (i.e., a game server) that both the main computer and the smartphone talk to. Using a serverless solution makes a lot of sense for a web game. And as we only have 48 hours here, less stuff to worry about is a big selling point too. Workers and Durable Objects also make it easy to keep the game running after the game jam, without having to pay for — and more importantly worry about — keeping servers running.

Setting up a line of communication

There are roughly two ways for browsers to communicate: through a shared connection (a game server somewhere) or a peer to peer connection, so browsers can talk directly to each other without a middleman by leveraging WebRTC DataChannels.

WebRTC can be very challenging to make reliable and may still need a proxy server for some especially problematic network setups behind multiple NATs. Setting up a WebRTC connection may have been the perfect solution for the lowest possible latency, but it was out of scope for such a short game jam.

The game we are creating has low latency requirements, when I tilt my phone the game should respond quickly. We can probably get away with anything under 100ms, although low double digits or less is definitely preferred! If I’m geographically located in one place and the game server is geographically close enough, then this game server will be able to pass messages from my smartphone to my laptop without too much delay. Edge computing is hot nowadays, and for this gaming use case it is not just a nice-to-have but also a necessity.

Enough background, let’s architect the system.

On-demand game rooms

The first thing I needed to set up was game rooms. Something that both the phone and the computer browsers could connect to, so they can pass messages between them.

Durable Objects allow us to create a large amount of small stateful “mini servers” or “rooms” that multiple clients can connect to simultaneously over WebSockets, providing perfect small on-demand game servers. Think of Durable Objects as a single thread of Javascript that runs in a data center close to where the user first asked for it to be created.

After the browser on the computer starts the game, it asks our Cloudflare Worker API to create a room for the current game session. This API request is a simple POST request, the server responds with a four character room code that uniquely identifies the room that was created. The reason we want the room code to be short is because the user may need to copy this code and type it into their smartphone if they are unable to scan a QR code.

Humans are notoriously bad at copying random character strings as different characters look alike, so we use a limited character set that excludes the most commonly confused characters:

const DICTIONARY = "2345679ADEFGHJKLMNPQRSTUVWXYZ"; // 29 chars (no 0, O, I, 1, B, 8)

A four character code will allow us to uniquely point to ~700,000 different rooms, that seems like it would be enough even if our game got quite popular! What’s more: these game sessions don’t last forever. After some period of time (say 24 hours) we can be certain enough that the game session has ended, and we can re-use that room code.

Room code coordination

In your Cloudflare Worker script, there are two ways to create a Durable Object: either we ask for one to be created with an ID generated from a name, or we ask for one to be created with a random unique ID. The naive solution would be to create a Durable Object with an ID generated from the room code. However, that is not a good idea here because a Durable Object gets created in a data center that is geographically close to the end user.

A problematic situation would be if a user in Mumbai requests a room and gets room code ABCD. Initially, they play the game for a bit, and it works great.

The issue comes a week later when that room code is reused for another player based in Los Angeles, The game room Durable Object will be revived in Mumbai and latency will be awful for our Los Angeles player. In the future, Durable Objects may get migrated between data centers, but that’s not yet guaranteed.

Instead, what we can do is create a new Durable Object with a random ID for every new game session and keep a mapping from the four character room code to this random ID. We are introducing some state in our system: we will need a central source of truth which is where Durable Objects can come to the rescue again.

We will solve this by creating a single “Room Hub” Durable Object that keeps track of this mapping from room code to Durable Object ID. This Durable Object will have two endpoints, one to request a new room and another to look up a room’s information.

Here’s our request handler for the Room Request endpoint (the argument is a Sunder Context, Sunder is the web framework I used for this project):

export async function handleRoomRequest(ctx: Context<Env>) {
    const now = Date.now();    
    const reqBody = await ctx.request.json();

    // We make some attempts to find a room that is available..
    const attempts = 5

    let roomCode: string;
    let roomStorageKey: string;

    for (let i = 0; i < attempts; i++) {
        roomCode = generateRoomCode();
        roomStorageKey = ROOM_STATE_PREFIX + roomCode;
        const room = await ctx.state.storage.get<RoomData>(roomStorageKey);
        if (room === undefined) {
            break;
        } else if (now - room.createdAt > MAX_ROOM_AGE) {
            await ctx.state.storage.delete(roomStorageKey);
            break;
        }
        if (i === attempts-1) {
            return ctx.throw("Couldn't find available room code :(");
        }
    }

    const roomData: RoomData = {
        roomCode: roomCode,
        durableObjectId: reqBody.durableObjectId,
        createdAt: now,
    }

    await ctx.state.storage.put<RoomData>(roomStorageKey, roomData);

    ctx.response.body = {
        room: roomData
    };
    ctx.response.status = HttpStatus.Created;
}

In a nutshell, we generate a few room codes until we find one that has never been used or hasn’t been used in a long enough time.

There is a subtle but important nuance in this code: the Durable Object gets created in the Cloudflare Worker that talks to our Room Hub, not in the Room Hub itself. Our Room Hub will run in a single data center somewhere on Cloudflare’s network. If we create the game room from there it may still be far away from our end user!

Looking up a room’s information is simpler, we return either the room data or status 404.

export async function handleRoomLookup(ctx: Context<Env, {roomCode: string}>) {
    const now = Date.now();

    let roomStorageKey = ROOM_STATE_PREFIX + ctx.params.roomCode;
    const roomData = await ctx.state.storage.get<RoomData>(roomStorageKey);

    if (roomData === undefined) {
        ctx.throw(404, "Room not found");
        return;
    }

    if (now - roomData.createdAt > MAX_ROOM_AGE) {
        // About time we cleaned it up.
        await ctx.state.storage.delete(roomStorageKey);
        ctx.response.status = HttpStatus.NotFound;
        return;
    }

    ctx.response.body = {
        room: roomData
    };
}

The smartphone browser needs to connect to that same room. To make things easy for the user we generate a four character room code which points at that specific “Game Room” Durable Object. This way the user can take their smartphone, navigate to the website address https://ld49.pages.dev, and enter the code “ABCD” (or more commonly, they scan a QR code with the link https://ld49.pages.dev?room=ABCD).

Game Room Durable Object

Our game room Durable Object can be pretty simple since it is only responsible for passing along messages from the smartphone to the laptop with the latest sensor readings. I was able to modify the Durable Objects chat room example to do exactly this — a good time saver for a game jam!

When a browser connects, they either connect as a “peer” or as a “host” role. Any messages sent by peers are forwarded to the host, and all messages from the host get forwarded to all peers. In this case, our host is the laptop browser running the game and the peer is the smartphone controller. Implementation-wise this means that we keep two lists of users: the peers and the hosts. Whenever a message comes in, we loop over the list to broadcast it to all connections of the other role. In practice, the code is a bit more involved to deal with users disconnecting.

Full Tilt is a singleplayer game, but adapting it to be a multiplayer game would be easy with this setup. Imagine a Mario Kart-like game that runs in your browser in which multiple friends can join using their smartphones as their steering wheel controller! Unfortunately there was not enough time in this game jam to make a polished game.

Front end

With the backend ready, we still need to create the actual game and the controller web app.

My initial plan was to create a game in which you fly a 3D plane by tilting your phone, collecting stars and completing aerobatic tricks. It would fit the theme “Unstable” as I expected this control method to be pretty flimsy! Since there was no time left to create anything close to that, it was time to cut scope.

I ended up using the Phaser game engine and put the entire system together in a Svelte app.   This was certainly a challenge, as I had only used Phaser once before many years ago and had never used Svelte. Luckily, I was able to put together something simple quickly enough: a snake-like game in which you move a thingy to collect blips that appear randomly on the screen.

In order for a game to be a game there needs to be some goal for the user, usually some game over condition. I changed the game to go faster and faster over time, added a score counter, and added a game over condition where you lose the game if you touch the edge of the screen. I made my “art” in MS Paint, generated some sound effects using the online tool sfxr, and “composed” the music soundtrack in Chrome’s Music Lab Song Maker.

Simultaneously I wrote a small client for my game server and duct-taped together the smartphone controller app which is powered by the browser’s DeviceMotion APIs. To distribute my game I used Cloudflare Pages, which worked like a charm the first time.

All done

And then the deadline was there — I barely made it, but I submitted something I was proud of. A not-so-great game, but with an interesting backend system and a novel input method. Do try the game yourself here, and the source code is available here (warning: it’s pretty hacky code of course!).

The reception of my co-jammers was great. While everybody agreed the game itself and its graphics were awful, it was novel. The game ended up rated first in the *Innovation* category for this game jam, out of hundreds of other games!

Finally, is this the future of game servers? For indie developers and smaller studios, setting up and maintaining a globally distributed fleet of game servers is both a huge distraction and cost. Serverless and in particular Durable Objects can provide an amazing solution.

But not every game is well-suited for a WebSocket-based backend. In some real-time games you are not interested in what happened a second ago and only the latest information matters. This is where the reliable and ordered nature of WebSockets can get in the way.

All in all my first impressions of Durable Objects are very positive, it is a great tool to have in your toolbelt for all kinds of web projects. You can now tackle problems that would otherwise take days in mere minutes. I am very excited to see what other problems will be made easy by Durable Objects, even those I haven’t even thought of yet.

Durable Objects — now Generally Available

Post Syndicated from Greg McKeon original https://blog.cloudflare.com/durable-objects-ga/

Durable Objects — now Generally Available

Durable Objects — now Generally Available

Full Stack Week is all about how developers are embracing the power of Cloudflare’s network to build entire applications that are global by default. The promise of Workers isn’t just improved latency — it’s fundamentally different programming paradigms that make developer’s lives easier and applications more resilient.

Last year, we announced Durable Objects — Cloudflare’s approach to coordinating state across Workers running at Cloudflare’s edge. Durable Objects let developers implement previously complex applications, like collaborative whiteboarding, game servers, or global queues, in just a few lines of code.

Today, we’re announcing that Durable Objects are generally available and production-ready for you to use!

What makes Durable Objects so cool?

For many traditional applications, state coordination happens through a database. Applications built on Workers present some unique challenges for a database — namely needing to handle global scale out-of-the-box and heavy concurrency that could lead to frequent transaction rollbacks when coordinating on shared keys. Databases themselves are hard to configure and scale, especially at global scale, so developers would need to tweak their database specifically for Workers’ access patterns.

Durable Objects present a simpler paradigm: write a JavaScript class, and your application can create named instances of that class — which are guaranteed to be unique across Cloudflare’s entire network. That instance is a Durable Object — Workers (and other Durable Objects!) can send messages to it via its ID. The Durable Object processes messages in-order and on a single-thread, allowing for coordination across messages. We also provide a strongly consistent storage API, which can store key-value pairs the object needs to make durable.

Take, for example, an online document editor.  A typical architecture would save the state of the document in a database and have users persist changes there.  This makes collaboration difficult, though — how can multiple users ensure that they all see the latest copy of changes to the document?

With Durable Objects, this is a much simpler problem.  By writing a Document class, you store the state of each document in-memory in a Durable Object.  As users connect, they’ll see the latest copy of the document — and can make their changes in-sync with other users. When users leave the document, the Durable Object will leave memory and stop incurring charges, while its state is persisted durably.  There’s no networking to configure, database to manage, or autoscaling policy to implement — it all just works.

While individual objects are single-threaded, Durable Objects’ design means a collection of objects can scale effectively infinitely. An object’s lifecycle is managed for you, meaning there’s no clean-up tasks to run or systems to scale down — Durable Objects can instantly scale to hundreds of thousands of requests per second, then scale back down with no developer interaction.

What have we been building since announcing Early Access?

First, we’ve kept busy improving reliability and performance. Durable Objects are behind a number of new products being developed at Cloudflare, including powering R2 storage and Cloudflare Waiting Room.

Specifically, Waiting Room uses Durable Objects to provide a strongly consistent view of the current number of users attempting to access a given site globally.  Storing this frequently updated state in a traditional database would be difficult to scale and be significantly harder to run globally.

Our customers have also embraced Durable Objects. We’ve seen a major gaming company build their new backend architecture on Durable Objects — coordinating both individual game state and multiplayer game lobbies.  The ability to dynamically scale without managing servers or databases made Durable Objects an easy choice for them, letting them grow their game with a relatively small team.

Customers have built more applications — from status page monitors to collaborative whiteboard applications.  We’ve seen particular interest in using Durable Objects with WebSockets to create entirely responsive applications and have published a reference architecture to help customers build this out further.

We’ve also gotten better at operating the system, particularly in response to large volumes of requests. Durable Objects can now serve hundreds of thousands of requests per second across objects, and hundreds of requests on a single object, making them production-ready for even the most demanding customers.

We’ve shipped Jurisdictional Restrictions, which bring the simplicity of scaling Durable Objects to compliance by letting developers tag a Durable Object with a region, ensuring it processes and stores data in that region.

We added a cache in front of Durable Object storage requests, making read and write operations blazing fast while also making it easier to write correct concurrent code.

Beyond that, we’ve made a number of smaller improvements that included simplified uploads of new Durable Objects classes, a UI in the dashboard and support for `wrangler dev` and `wrangler tail` for live debugging.

What’s next for Durable Objects?

We’re continuing to work on making Durable Objects the easiest platform for building infinitely-scalable applications.

Today, Durable Objects scale well when objects can be partitioned, but individual objects are limited to a single execution thread. Many workloads could be scaled across multiple threads, providing read-only access to an object’s state and choosing to only synchronize when mutating state. We’re calling this replication for Durable Objects, and we’re working on it now.

We’re also working on adding an API for a guaranteed callback to a Durable Object, letting developers wake a Durable Object at a specified time in the future to run a function. This simplifies lifecycle management, making it easy to build primitives like reliable queues on top of Durable Objects.

We’re also looking into how to better geo-distribute objects, including the vision for automatic migration of objects we talked about in our initial announcement.

Have something you’d like to see us add? Shoot us an email or a tweet!

How do I use Durable Objects?

Head over to the Cloudflare Dashboard to enable Durable Objects and opt in to pricing, then check out our sample chat application and reference architecture here!

Happy building!

Durable Objects: Easy, Fast, Correct — Choose three.

Post Syndicated from Kenton Varda original https://blog.cloudflare.com/durable-objects-easy-fast-correct-choose-three/

Durable Objects: Easy, Fast, Correct — Choose three.

Durable Objects: Easy, Fast, Correct — Choose three.

Storage in distributed systems is surprisingly hard to get right. Distributed databases and consensus are well-known to be extremely hard to build. But, application code isn’t necessarily easy either. There are many ways in which apps that use databases can have subtle timing bugs that could result in inconsistent results, or even data loss. Worse, these problems can be very hard to test for, as they’ll often manifest only under heavy load, or only after a sudden machine failure.

Up until recently, Durable Objects were no exception. A Durable Object is a special kind of Cloudflare Worker that has access to persistent storage and processes requests in one of Cloudflare’s points of presence. Each Object has its own private storage, accessible through a classical key/value storage API. Like any classical database API, this storage API had to be used carefully to avoid possible race conditions and data loss, especially when performance mattered. And like any classical database API, many apps got it wrong.

However, rather than fix the apps, we decided to fix the model. Last month, we rolled out deep changes to the Durable Objects runtime such that many applications which previously contained subtle race conditions are now correct by default, and many that were previously slow are now fast. Developers can now write their code in an intuitive way, and have it work. No changes at all are needed to your code in order to take advantage of these new features.

So, let me tell you about what changed…

Background: Durable Objects are Single-Threaded

To understand what changed, it’s necessary to first understand Durable Objects. For a full introduction, see the Durable Objects announcement blog post.

The most important point is: Each Durable Object runs in exactly one location, in one single thread, at a time. Each object has its own private on-disk storage. This is a very different situation from a typical database, where many clients may be accessing the same data. In Durable Objects, any particular piece of data belongs to exactly one thread at a time.

Because a single Durable Object is single-threaded, it’s possible, and even encouraged, to keep state and perform synchronization in memory. This is, indeed, the killer feature of Durable Objects. With classical databases, in-memory state is extremely difficult to keep synchronized between all database clients. But with Durable Objects, since each piece of data belongs to a specific thread, this synchronization is easy.

However, interacting with the disk is still an I/O (input/output) operation, which means that each operation returns a Promise which you must await. As we’ll see, this re-introduces some of the synchronization difficulties that we were trying to avoid. However, it turns out, we can solve these difficulties within the system itself, without bothering application developers.

An Example

Consider this code:

// Used to be slow and racy -- but not anymore!
async function getUniqueNumber() {
  let val = await this.storage.get("counter");
  await this.storage.put("counter", val + 1);
  return val;
}

At first glance, this seems like reasonable code that returns a unique number each time it is called (incrementing each time).

Unfortunately, before now, this code had two problems:

  1. It had a subtle race condition (even though Durable Objects are single-threaded!).
  2. It was kind of slow.

The Race Condition

A race condition occurs when two operations running concurrently might interfere with each other in a way that makes them behave incorrectly. Race conditions are commonly associated with code that uses multiple threads.

JavaScript, however, famously does not use threads. Instead, it uses event-driven programming, with callbacks. It’s not possible for two pieces of JavaScript code to be running "at the same time" in the same isolate (and Durable Objects promises that no other isolate could possibly be accessing the same storage). Does that mean that race conditions aren’t a problem in JavaScript, the way they are in multi-threaded apps?

Unfortunately, it does not. The problem is, the code above is an async function, containing two await statements. Each time await is used, execution pauses, waiting for the specified Promise to complete.

In the meantime, though, other code can run! For example, the Durable Object might receive two requests at the same time. If each of them calls getUniqueNumber(), then the two calls might be interleaved. Each time one call performs an await, execution may switch to the other call. So, the two calls might end up looking like this:

Request 1 timeline Request 2 timeline
async function getUniqueNumber() {
  let val = await this.storage.get("counter");


async function getUniqueNumber() {
  let val = await this.storage.get("counter");
  await this.storage.put("counter", val + 1);
 
 
  await this.storage.put("counter", val + 1);
  return val;
}


  return val;
}

There’s a big problem here: Both of these two calls will call get("counter") before either of them calls put("counter", val + 1). That means, both of them will return the same value!

This problem is especially bad because it only happens when multiple requests are being handled at the same time — and even then, only sometimes. It is very hard to test for this kind of problem, and everything might seem just fine when the application is deployed, as long as it isn’t getting too much traffic. But one day, when a lot of visitors try to use the same object at the same time, all of a sudden getUniqueNumber() starts returning duplicates!

The Slowness

To add insult to injury, getUniqueNumber() was (until recently) pretty slow. The problem is, it has to do two round trips to storage — a get() and a put(). The get() might typically take a couple milliseconds. The put(), however, will take much longer, probably tens of milliseconds.

Why is put() so slow? Because we don’t want to lose data. The worst thing an application can do is tell the user that their action was successful when it wasn’t. If, for some reason, a write cannot be completed, then it’s imperative that the application presents an error to the user, so that the user knows that something is wrong and they’ll have to try again or look for a fix.

In order to make sure an application does not prematurely report success to the user, await put() has to make sure it doesn’t return until the data is actually safe on disk. Disks are slow, so this might take a while.

But that’s not all. Disks can fail. In order for the data to be really safe, we have to write the same data on multiple disks, in multiple machines. That means we have to wait for some network traffic.

But that’s still not all. What if a meteor were to come out of the sky and land on a Cloudflare data center, completely destroying it? Or, more likely, what if the power or network connection failed? We don’t want a user’s data to be lost in this case, or even temporarily become unavailable. Therefore, Durable Object data is replicated to multiple Cloudflare locations. This requires communicating across long distances before any write can be confirmed. There is little we can do to make this faster, the speed of light being what it is.

A call to getUniqueNumber() will therefore always take tens of milliseconds. If an application calls it multiple times, awaiting each call before beginning the next, it can easily become very slow very quickly. Or, at least, that was the case before our recent changes.

The Wrong Fixes

There are several ways that an application could fix these problems, but all of them have their own issues.

Transactions?

Many databases offer "transactions". A transaction allows an application to make sure some operation completes "atomically", with no interference from concurrent operations.

The Durable Objects storage API has always supported transactions. We could use them to fix our getUniqueNumber() implementation like so:

// No more race condition... but slow and complicated.
async function getUniqueNumber() {
  let val;
  await this.storage.transaction(async (txn) => {
    val = await txn.get("counter");
    await txn.put("counter", val + 1);
  });
  return val;
}

This fixes our race condition. Now, if getUniqueNumber() is called multiple times concurrently such that the storage operations interleave, the system will detect the problem. One of the concurrent calls will be chosen to be the "winner", and will complete normally. The other calls will be canceled and retried, so that they can see the value written by the first call.

This fixes our problems! But, at some cost:

  • getUniqueNumber() is now even slower than it was before. The difference typically won’t be huge, but setting up a transaction does require some additional coordination in the database. Of course, if the transaction needs to be retried, then it may end up being much slower. And retries will tend to happen more when load gets high… the worst possible time.
  • Speaking of retries, many developers might not realize that the transaction callback can be called multiple times. It’s difficult to test for this, since retries will only happen when concurrent operations cause conflicts. The problem is especially acute when the application is trying to synchronize not just on-disk state, but also in-memory state — if the transaction callback modifies in-memory state, it must be careful to ensure that its changes are idempotent. The need for idempotency may not be top of mind for most developers, and tests won’t catch the problem, making it very easy to end up deploying buggy code.

So we solved our problem, but we did it with a foot-gun. If we keep using the foot-gun, we’re probably going to shoot our own feet eventually.

Is there another way?
In-memory caching?
Durable Objects’ superpower is their in-memory state. Each object has only one active instance at any particular time. All requests sent to that object are handled by that same instance. That means, you can store some state in memory.

// Much faster! But (used to be) wrong.
async function getUniqueNumber() {
  if (this.val === undefined) {
    this.val = await this.storage.get("counter");
  }

  let result = this.val;
  ++this.val;
  this.storage.put("counter", this.val);
  return result;
}

This code is MUCH faster than the previous implementation, because it stores the value in memory. In fact, after the function runs once, further calls won’t wait for any I/O at all — they will return immediately. This is because by caching the value in memory, we avoid waiting for a get() (except for the first time), and we don’t wait for the put() either, trusting that it will complete asynchronously later on.

Returning immediately also means that there’s no opportunity for concurrency, so the calls that return immediately will always return unique numbers! This means that not only is this implementation faster than our original implementation, it is also more correct. This is only possible because the Durable Objects platform guarantees that there will only be one instance, and therefore only one copy of this.val.

Unfortunately, there are two problems with this code:

  • We still have a race condition on initialization. If the first two calls to getUniqueNumber() happen to occur at about the same time, then initialization will be performed multiple times. The second call will likely clobber what the first call did, and the two calls will end up returning the same number. We could solve this problem by making initialization more complicated — the first call could create an initialization promise, and other concurrent calls could wait on it, so that initialization really only happens once. But this creates even deeper complexity: What if initialization fails for some reason? The object could be placed in a permanently broken state. It’s possible to get this right, but it’s surprisingly tricky.
  • Because we don’t wait for the put() to report success, it’s possible that it could be silently lost. For example, if the machine hosting the Durable Object suffered a sudden power failure, then the Durable Object would be transferred to some other machine. When it starts up there, calls to getUniqueNumber() might return numbers that had already been returned under the old instance before it failed, because the put()s hadn’t actually completed before the failure occurred. But if we await the put(), then our function becomes slow again, and creates more opportunities for race conditions (e.g. in the calling code).

Our answer: Make it automatic

When looking at this, we had two options:

  1. Try to carefully document these problems and educate developers about them, so that they could write code that does the right thing.
  2. Change the system so that naturally-written code just does the right thing by default — and runs quickly.

We chose option 2. We accomplished this in three parts.

Part 1: Input Gates

Let’s go back to our original example. Can we make this example "just work", even in the face of concurrent requests?

// Can this "just work" please?
async function getUniqueNumber() {
  let val = await this.storage.get("counter");
  await this.storage.put("counter", val + 1);
  return val;
}

It turns out we can! We create a new rule:

Input gates: While a storage operation is executing, no events shall be delivered to the object except for storage completion events. Any other events will be deferred until such a time as the object is no longer executing JavaScript code and is no longer waiting for any storage operations. We say that these events are waiting for the "input gate" to open.

If we do this, then our storage operations above are no longer an opportunity for concurrency. Our concurrent requests now look like this:

Request 1 timeline Request 2 timeline
async function getUniqueNumber() {
  let val = await this.storage.get("counter");


// Request 2 delivery is blocked because
// request 1 is waiting for storage.
  await this.storage.put("counter", val + 1);


// Request 2 delivery is blocked because
// request 1 is waiting for storage.
  return val;
}


async function getUniqueNumber() {
  let val = await this.storage.get("counter");
  await this.storage.put("counter", val + 1);
  return val;
}

The two calls return unique numbers, as expected. Hooray! (Unfortunately, we did it by delaying the second request, creating latency and reducing throughput — but we’ll address that in part 3, below.)

Note that our rule does not preclude making multiple concurrent requests to storage at the same time. You can still say:

let promise1 = this.storage.get("foo");
let promise2 = this.storage.put("bar", 123);
await promise1;
frob();
await promise2;

Here, the get() and put() execute concurrently. Moreover, the call to frob() may execute before the put() has completed (but strictly after the get() completes, since we awaited that promise). However, no other event — such as receiving a new request — can unexpectedly happen in the meantime.

On the other hand, the rule protects you not just against concurrent incoming requests, but also concurrent responses to outgoing requests. For example, say you have:

async function task1() {
  await fetch("https://example.com/api1");
  return await this.getUniqueNumber();
}
async function task2() {
  await fetch("https://example.com/api2");
  return await this.getUniqueNumber();
}
let promise1 = task1();
let promise2 = task2();
let val1 = await promise1;
let val2 = await promise2;

This code launches two fetch() calls concurrently. After each fetch completes, getUniqueNumber() is invoked. Could the two calls interfere with each other?

No, they will not. The completion of a fetch() is itself a kind of event. Our rule states that such events cannot be delivered while storage events are in progress. When the first of the two fetches returns, the app calls getUniqueNumber(), which starts performing some storage operations. If the second fetch() also returns while these storage operations are still outstanding, that return will be deferred until after the storage operations are done. Once again, our code ends up correct!

At this point, the async programming experts in the audience are probably starting to feel like something is fishy here. Indeed, there is a catch. What if we do:

// Still a problem even with input gates.
let promise1 = getUniqueNumber();
let promise2 = getUniqueNumber();
let val1 = await promise1;
let val2 = await promise2;

In this case, there is, in fact, a problem. Two calls to getUniqueNumber() are initiated by the same event. The application does not await the first call before starting the second, so the two calls end up running concurrently. Our special rule doesn’t protect us here, because there is no incoming event that can be deferred between when the two calls are made. From the system’s point of view, there’s no way to distinguish this code from code which legitimately decided to perform two storage operations in parallel.

As such, in this case, the two calls to getUniqueNumber() will interfere with each other. However, this problem is far less likely to come about by accident, and is far easier to catch in testing. This bug is deterministic, not caused by the unpredictable timing of network events. We consider this an acceptable caveat in order to solve the larger problem posed by concurrent requests.

Part 2: Output Gates

Let’s go back to our in-memory caching example. Can we make it work?

// Can we make this "just work"?
async function getUniqueNumber() {
  if (this.val === undefined) {
    this.val = await this.storage.get("counter");
  }

  let result = this.val;
  ++this.val;
  this.storage.put("counter", this.val);
  return result;
}

With input gates (part 1), we’ve solved one of the two problems this code had: the race condition of initialization. We no longer need to worry that two requests will call this at the same time, leading this.val to be initialized twice.

However, the problem with not awaiting the put() is still there. If we don’t await it, then we could lose data. If we do await it, then the call is slow.

We make another new rule:

Output gates: When a storage write operation is in progress, any new outgoing network messages will be held back until the write has completed. We say that these messages are waiting for the "output gate" to open. If the write ultimately fails, the outgoing network messages will be discarded and replaced with errors, while the Durable Object will be shut down and restarted from scratch.

With this rule, we no longer have to await the result of put(). Our code can happily continue executing and just assume the put() will succeed. If the put() doesn’t succeed, then anything the application does here will never be observable to the rest of the world anyway. For example, if the app prematurely sends a response to the user saying that the operation succeeded, this response will not actually be delivered until after the put() completes successfully. So, by the time the user receives the message, it is no longer "premature"! In the very rare event that the write operation fails, the user will not receive the premature confirmation at all.

Note that output gates apply not only to responses sent back to a client, but also to new outgoing requests made with fetch() — those requests will be delayed from being sent until all prior writes are confirmed. So, once again, it is impossible for anything else in the world to observe a premature confirmation.

With this change, our getUniqueNumber() implementation with in-memory caching is now fully correct, while retaining most of its speed advantage over the non-caching implementation. Except for the very first call, the application will never be blocked waiting for getUniqueNumber() to finish. The final response from the app to the client will be delayed pending write confirmation, but that write can be performed in parallel with any writes the application performs after getUniqueNumber() completes.

Part 3: Automatic in-memory caching

Our in-memory caching example now works great. But, it’s still a little bit complicated and unnatural to write. Let’s go back to our original, simple code one more time… can we make it fast by default?

// Can we make this not just work, but just work FAST?
async function getUniqueNumber() {
  let val = await this.storage.get("counter");
  await this.storage.put("counter", val + 1);
  return val;
}

The answer to this part is a classic one: we can add automatic caching to the storage layer, just like most operating systems do for disk storage.

We have rolled out an in-memory caching layer for Durable Objects. This layer keeps up to several megabytes worth of data directly in memory in the process where the object runs.

When a get() requests a key that is in cache, the operation returns immediately, without even context-switching out of the thread and isolate where the object is hosted. If the key is not in cache, then a storage request will still be needed, but reads complete relatively quickly.

Better yet, put() requests now always complete "instantaneously". A put() simply writes to cache. We rely on output gates ("part 2", above) to prevent the premature confirmation of writes to any external party. Writes will be coalesced (even if you await them), so that the output gate waits only for O(1) network round trips of latency, not O(n).

Moreover, because get() and put() now complete instantly in most or all cases, the negative impact of input gates on throughput is largely mitigated, because the gate now spends relatively little time blocked.

With Durable Objects built-in caching, our simple code is now just as fast as our code that manually implemented in-memory caching. Combined with input and output gates, our code is now simple, fast, and correct, all at the same time.

Bonus Correctness

Our caching layer provides some bonus consistency guarantees, in addition to performance.

First, writes are automatically coalesced. That is, if you perform multiple put() or delete() operations without awaiting them or anything else in between, then the operations are automatically grouped together and stored atomically. In the case of a sudden power failure, after coming back up, either all of the writes will have been stored, or none of them will. For example:

// Move a value from "foo" to "bar".
let val = await this.storage.get("foo");

this.storage.delete("foo");
this.storage.put("bar", val);
// There's no possibility of data loss, because the delete() and the
// following put() are automatically coalesced into one atomic
// operation. This is true as long as you do not `await` anything
// in between.

Second, the API is also able to provide stronger ordering guarantees for reads. Previously, overlapping storage operations did not have guaranteed ordering. For example, if you issued a get() and a put() on the same key at the same time (without awaiting one before starting the other), then it was not deterministic whether the get() might return the value written by the put() — regardless of the ordering of the statements in your code. The caching layer fixes this. Now, operations are performed in exactly the order in which they were initiated, regardless of when they complete.

These two features eliminate more subtle bugs that might otherwise be hard to catch in testing, so that you don’t have to be a database expert to write code that works.

Optional Bypass

We expect gates and caching will be a win in the vast majority of use cases, but not always. In some use cases, concurrency won’t lead to any problems, and so blocking it may be a loss. Sometimes, the application is OK with prematurely confirming writes in order to minimize latency. And sometimes, caching may just waste memory because the same keys are not frequently accessed.

For those cases, we offer explicit bypasses:

this.storage.get("foo", {allowConcurrency: true, noCache: true});
this.storage.put("foo", "bar", {allowUnconfirmed: true, noCache: true});

Developers who have taken the time to think carefully about these issues can use these flags to tune performance to their specific needs. For those who don’t want to think about it, the defaults should work well.

Conclusion

Concurrency is hard. It doesn’t matter if you’re a novice or an expert: even experts regularly get it wrong. It’s difficult to think about all the ways that concurrent operations might overlap to corrupt your application state.

The traditional answer has been to make applications stateless, and defer all concurrency control to the database layer using transactions. However, transactions are slow, which is a big reason why so many web applications today take hundreds of milliseconds or more to respond to basic actions.

Durable Objects are all about state. By keeping state in memory in addition to on disk, and directing requests for the same data to be coordinated through the same instance, we can make applications much faster. But until recently, this was extremely tricky to get right.

With input gates, output gates, and caching, code written in the most intuitive way now "just works", and runs fast. This means you can focus on building your application, without wasting time optimizing I/O performance and debugging obscure race conditions.

Building Waiting Room on Workers and Durable Objects

Post Syndicated from Fabienne Semeria original https://blog.cloudflare.com/building-waiting-room-on-workers-and-durable-objects/

Building Waiting Room on Workers and Durable Objects

Building Waiting Room on Workers and Durable Objects

In January, we announced the Cloudflare Waiting Room, which has been available to select customers through Project Fair Shot to help COVID-19 vaccination web applications handle demand. Back then, we mentioned that our system was built on top of Cloudflare Workers and the then brand new Durable Objects. In the coming days, we are making Waiting Room available to customers on our Business and Enterprise plans. As we are expanding availability, we are taking this opportunity to share how we came up with this design.

What does the Waiting Room do?

You may have seen lines of people queueing in front of stores or other buildings during sales for a new sneaker or phone. That is because stores have restrictions on how many people can be inside at the same time. Every store has its own limit based on the size of the building and other factors. If more people want to get inside than the store can hold, there will be too many people in the store.

The same situation applies to web applications. When you build a web application, you have to budget for the infrastructure to run it. You make that decision according to how many users you think the site will have. But sometimes, the site can see surges of users above what was initially planned. This is where the Waiting Room can help: it stands between users and the web application and automatically creates an orderly queue during traffic spikes.

The main job of the Waiting Room is to protect a customer’s application while providing a good user experience. To do that, it must make sure that the number of users of the application around the world does not exceed limits set by the customer. Using this product should not degrade performance for end users, so it should not add significant latency and should admit them automatically. In short, this product has three main requirements: respect the customer’s limits for users on the web application, keep latency low, and provide a seamless end user experience.

When there are more users trying to access the web application than the limits the customer has configured, new users are given a cookie and greeted with a waiting room page. This page displays their estimated wait time and automatically refreshes until the user is automatically admitted to the web application.

Building Waiting Room on Workers and Durable Objects

Configuring Waiting Rooms

The important configurations that define how the waiting room operates are:

  1. Total Active Users – the total number of active users that can be using the application at any given time
  2. New Users Per Minute – how many new users per minute are allowed into the application, and
  3. Session Duration – how long a user session lasts. Note: the session is renewed as long as the user is active. We terminate it after Session Duration minutes of inactivity.

How does the waiting room work?

If a web application is behind Cloudflare, every request from an end user to the web application will go to a Cloudflare data center close to them. If the web application enables the waiting room, Cloudflare issues a ticket to this user in the form of an encrypted cookie.

Building Waiting Room on Workers and Durable Objects
Waiting Room Overview

At any given moment, every waiting room has a limit on the number of users that can go to the web application. This limit is based on the customer configuration and the number of users currently on the web application. We refer to the number of users that can go into the web application at any given time as the number of user slots. The total number of users slots is equal to the limit configured by the customer minus the total number of users that have been let through.

When a traffic surge happens on the web application the number of user slots available on the web application keeps decreasing. Current user sessions need to end before new users go in. So user slots keep decreasing until there are no more slots. At this point the waiting room starts queueing.

Building Waiting Room on Workers and Durable Objects

The chart above is a customer’s traffic to a web application between 09:40 and 11:30. The configuration for total active users is set to 250 users (yellow line). As time progresses there are more and more users on the application. The number of user slots available (orange line) in the application keeps decreasing as more users get into the application (green line). When there are more users on the application, the number of slots available decreases and eventually users start queueing (blue line). Queueing users ensures that the total number of active users stays around the configured limit.

To effectively calculate the user slots available, every service at the edge data centers should let its peers know how many users it lets through to the web application.

Coordination within a data center is faster and more reliable than coordination between many different data centers. So we decided to divide the user slots available on the web application to individual limits for each data center. The advantage of doing this is that only the data center limits will get exceeded if there is a delay in traffic information getting propagated. This ensures we don’t overshoot by much even if there is a delay in getting the latest information.

The next step was to figure out how to divide this information between data centers. For this we decided to use the historical traffic data on the web application. More specifically, we track how many different users tried to access the application across every data center in the preceding few minutes. The great thing about historical traffic data is that it’s historical and cannot change anymore. So even with a delay in propagation, historical traffic data will be accurate even when the current traffic data is not.

Let’s see an actual example: the current time is Thu, 27 May 2021 16:33:20 GMT. For the minute Thu, 27 May 2021 16:31:00 GMT there were 50 users in Nairobi and 50 in Dublin. For the minute Thu, 27 May 2021 16:32:00 GMT there were 45 users in Nairobi and 55 in Dublin. This was the only traffic on the application during that time.

Every data center looks at what the share of traffic to each data center was two minutes in the past. For Thu, 27 May 2021 16:33:20 GMT that value is Thu, 27 May 2021 16:31:00 GMT.

Thu, 27 May 2021 16:31:00 GMT: 
{
  Nairobi: 0.5, //50/100(total) users
  Dublin: 0.5,  //50/100(total) users
},
Thu, 27 May 2021 16:32:00 GMT: 
{
  Nairobi: 0.45, //45/100(total) users
  Dublin: 0.55,  //55/100(total) users
}

For the minute Thu, 27 May 2021 16:33:00 GMT, the number of user slots available will be divided equally between Nairobi and Dublin as the traffic ratio for Thu, 27 May 2021 16:31:00 GMT is 0.5 and 0.5. So, if there are 1000 slots available, Nairobi will be able to send 500 and Dublin can send 500.

For the minute Thu, 27 May 2021 16:34:00 GMT, the number of user slots available will be divided using the ratio 0.45 (Nairobi) to 0.55 (Dublin). So if there are 1000 slots available, Nairobi will be able to send 450 and Dublin can send 550.

Building Waiting Room on Workers and Durable Objects

The service at the edge data centers counts the number of users it let into the web application. It will start queueing when the data center limit is approached. The presence of limits for the data center that change based on historical traffic helps us to have a system that doesn’t need to communicate often between data centers.

Clustering

In order to let people access the application fairly we need a way to keep track of their position in the queue. A bucket has an identifier (bucketId) calculated based on the time the user tried to visit the waiting room for the first time.  All the users who visited the waiting room between 19:51:00 and 19:51:59 are assigned to the bucketId 19:51:00. It’s not practical to track every end user in the waiting room individually. When end users visit the application around the same time, they are given the same bucketId. So we cluster users who came around the same time as one time bucket.

We mentioned an encrypted cookie that is assigned to the user when they first visit the waiting room. Every time the user comes back, they bring this cookie with them. The cookie is a ticket for the user to get into the web application. The content below is the typical information the cookie contains when visiting the web application. This user first visited around Wed, 26 May 2021 19:51:00 GMT, waited for around 10 minutes and got accepted on Wed, 26 May 2021 20:01:13 GMT.

{
  "bucketId": "Wed, 26 May 2021 19:51:00 GMT",
  "lastCheckInTime": "Wed, 26 May 2021 20:01:13 GMT",
  "acceptedAt": "Wed, 26 May 2021 20:01:13 GMT",
 }

Here

bucketId – the bucketId is the cluster the ticket is assigned to. This tracks the position in the queue.

acceptedAt – the time when the user got accepted to the web application for the first time.

lastCheckInTime – the time when the user was last seen in the waiting room or the web application.

Once a user has been let through to the web application, we have to check how long they are eligible to spend there. Our customers can customize how long a user spends on the web application using Session Duration. Whenever we see an accepted user we set the cookie to expire Session Duration minutes from when we last saw them.

Waiting Room State

Previously we talked about the concept of user slots and how we can function even when there is a delay in communication between data centers. The waiting room state helps to accomplish this. It is formed by historical data of events happening in different data centers. So when a waiting room is first created, there is no waiting room state as there is no recorded traffic. The only information available is the customer’s configured limits. Based on that we start letting users in. In the background the service (introduced later in this post as Data Center Durable Object) running in the data center periodically reports about the tickets it has issued to a co-ordinating service and periodically gets a response back about things happening around the world.

As time progresses more and more users with different bucketIds show up in different parts of the globe. Aggregating this information from the different data centers gives the waiting room state.

Let’s look at an example: there are two data centers, one in Nairobi and the other in Dublin. When there are no user slots available for a data center, users start getting queued. Different users who were assigned different bucketIds get queued. The data center state from Dublin looks like this:

activeUsers: 50,
buckets: 
[  
  {
    key: "Thu, 27 May 2021 15:55:00 GMT",
    data: 
    {
      waiting: 20,
    }
  },
  {
    key: "Thu, 27 May 2021 15:56:00 GMT",
    data: 
    {
      waiting: 40,
    }
  }
]

The same thing is happening in Nairobi and the data from there looks like this:

activeUsers: 151,
buckets: 
[ 
  {
    key: "Thu, 27 May 2021 15:54:00 GMT",
    data: 
    {
      waiting: 2,
    },
  } 
  {
    key: "Thu, 27 May 2021 15:55:00 GMT",
    data: 
    {
      waiting: 30,
    }
  },
  {
    key: "Thu, 27 May 2021 15:56:00 GMT",
    data: 
    {
      waiting: 20,
    }
  }
]

This information from data centers are reported in the background and aggregated to form a data structure similar to the one below:

activeUsers: 201, // 151(Nairobi) + 50(Dublin)
buckets: 
[  
  {
    key: "Thu, 27 May 2021 15:54:00 GMT",
    data: 
    {
      waiting: 2, // 2 users from (Nairobi)
    },
  }
  {
    key: "Thu, 27 May 2021 15:55:00 GMT", 
    data: 
    {
      waiting: 50, // 20 from Nairobi and 30 from Dublin
    }
  },
  {
    key: "Thu, 27 May 2021 15:56:00 GMT",
    data: 
    {
      waiting: 60, // 20 from Nairobi and 40 from Dublin
    }
  }
]

The data structure above is a sorted list of all the bucketIds in the waiting room. The waiting field has information about how many people are waiting with a particular bucketId. The activeUsers field has information about the number of users who are active on the web application.

Imagine for this customer, the limits they have set in the dashboard are

Total Active Users – 200
New Users Per Minute – 200

As per their configuration only 200 customers can be at the web application at any time. So users slots available for the waiting room state above are 200 – 201(activeUsers) = -1. So no one can go in and users get queued.

Now imagine that some users have finished their session and activeUsers is now 148.

Now userSlotsAvailable = 200 – 148 = 52 users. We should let 52 of the users who have been waiting the longest into the application. We achieve this by giving the eligible slots to the oldest buckets in the queue. In the example below 2 users are waiting from bucket Thu, 27 May 2021 15:54:00 GMT and 50 users are waiting from bucket Thu, 27 May 2021 15:55:00 GMT. These are the oldest buckets in the queue who get the eligible slots.

activeUsers: 148,
buckets: 
[  
  {
    key: "Thu, 27 May 2021 15:54:00 GMT",
    data: 
    {
      waiting: 2,
      eligibleSlots: 2,
    },
  }
  {
    key: "Thu, 27 May 2021 15:55:00 GMT",
    data: 
    {
      waiting: 50,
      eligibleSlots: 50,
    }
  },
  {
    key: "Thu, 27 May 2021 15:56:00 GMT",
    data: 
    {
      waiting: 60,
      eligibleSlots: 0,
    }
  }
]

If there are eligible slots available for all the users in their bucket, then they can be sent to the web application from any data center. This ensures the fairness of the waiting room.

There is another case that can happen where we do not have enough eligible slots for a whole bucket. When this happens things get a little more complicated as we cannot send everyone from that bucket to the web application. Instead, we allocate a share of eligible slots to each data center.

key: "Thu, 27 May 2021 15:56:00 GMT",
data: 
{
  waiting: 60,
  eligibleSlots: 20,
}

As we did before, we use the ratio of past traffic from each data center to decide how many users it can let through. So if the current time is Thu, 27 May 2021 16:34:10 GMT both data centers look at the traffic ratio in the past at Thu, 27 May 2021 16:32:00 GMT and send a subset of users from those data centers to the web application.

Thu, 27 May 2021 16:32:00 GMT: 
{
  Nairobi: 0.25, // 0.25 * 20 = 5 eligibleSlots
  Dublin: 0.75,  // 0.75 * 20 = 15 eligibleSlots
}

Estimated wait time

When a request comes from a user we look at their bucketId. Based on the bucketId it is possible to know how many people are in front of the user’s bucketId from the sorted list. Similar to how we track the activeUsers we also calculate the average number of users going to the web application per minute. Dividing the number of people who are in front of the user by the average number of users going to the web application gives us the estimated time. This is what is shown to the user who visits the waiting room.

avgUsersToWebApplication:  30,
activeUsers: 148,
buckets: 
[  
  {
    key: "Thu, 27 May 2021 15:54:00 GMT",
    data: 
    {
      waiting: 2,
      eligibleSlots: 2,
    },
  }
  {
    key: "Thu, 27 May 2021 15:55:00 GMT",
    data: 
    {
      waiting: 50,
      eligibleSlots: 50,
    }
  },
  {
    key: "Thu, 27 May 2021 15:56:00 GMT",
    data: 
    {
      waiting: 60,
      eligibleSlots: 0,
    }
  }
]

In the case above for a user with bucketId Thu, 27 May 2021 15:56:00 GMT, there are 60 users ahead of them. With 30 activeUsersToWebApplication per minute, the estimated time to get into the web application is 60/30 which is 2 minutes.

Implementation with Workers and Durable Objects

Now that we have talked about the user experience and the algorithm, let’s focus on the implementation. Our product is specifically built for customers who experience high volumes of traffic, so we needed to run code at the edge in a highly scalable manner. Cloudflare has a great culture of building upon its own products, so we naturally thought of Workers. The Workers platform uses Isolates to scale up and can scale horizontally as there are more requests.

The Workers product has an ecosystem of tools like wrangler which help us to iterate and debug things quickly.

Workers also reduce long-term operational work.

For these reasons, the decision to build on Workers was easy. The more complex choice in our design was for the coordination. As we have discussed before, our workers need a way to share the waiting room state. We need every worker to be aware of changes in traffic patterns quickly in order to respond to sudden traffic spikes. We use the proportion of traffic from two minutes before to allocate user slots among data centers, so we need a solution to aggregate this data and make it globally available within this timeframe. Our design also relies on having fast coordination within a data center to react quickly to changes. We considered a few different solutions before settling on Cache and Durable Objects.

Idea #1: Workers KV

We started to work on the project around March 2020. At that point, Workers offered two options for storage: the Cache API and KV. Cache is shared only at the data center level, so for global coordination we had to use KV. Each worker writes its own key to KV that describes the requests it received and how it processed them. Each key is set to expire after a few minutes if the worker stopped writing. To create a workerState, the worker periodically does a list operation on the KV namespace to get the state around the world.

Building Waiting Room on Workers and Durable Objects
Design using KV

This design has some flaws because KV wasn’t built for a use case like this. The state of a waiting room changes all the time to match traffic patterns. Our use case is write intensive and KV is intended for read-intensive workflows. As a consequence, our proof of concept implementation turned out to be more expensive than expected. Moreover, KV is eventually consistent: it takes time for information written to KV to be available in all of our data centers. This is a problem for Waiting Room because we need fine-grained control to be able to react quickly to traffic spikes that may be happening simultaneously in several locations across the globe.

Idea #2: Centralized Database

Another alternative was to run our own databases in our core data centers. The Cache API in Workers lets us use the cache directly within a data center. If there is frequent communication with the core data centers to get the state of the world, the cached data in the data center should let us respond with minimal latency on the request hot path. There would be fine-grained control on when the data propagation happens and this time can be kept low.

Building Waiting Room on Workers and Durable Objects
Design using Core Data centers‌‌

As noted before, this application is very write-heavy and the data is rather short-lived. For these reasons, a standard relational database would not be a good fit. This meant we could not leverage the existing database clusters maintained by our in-house specialists. Rather, we would need to use an in-memory data store such as Redis, and we would have to set it up and maintain it ourselves. We would have to install a data store cluster in each of our core locations, fine tune our configuration, and make sure data is replicated between them. We would also have to create a  proxy service running in our core data centers to gate access to that database and validate data before writing to it.

We could likely have made it work, at the cost of substantial operational overhead. While that is not insurmountable, this design would introduce a strong dependency on the availability of core data centers. If there were issues in the core data centers, it would affect the product globally whereas an edge-based solution would be more resilient. If an edge data center goes offline Anycast takes care of routing the traffic to the nearby data centers. This will ensure a web application will not be affected.

The Scalable Solution: Durable Objects

Around that time, we learned about Durable Objects. The product was in closed beta back then, but we decided to embrace Cloudflare’s thriving dogfooding culture and did not let that deter us. With Durable Objects, we could create one global Durable Object instance per waiting room instead of maintaining a single database. This object can exist anywhere in the world and handle redundancy and availability. So Durable Objects give us sharding for free. Durable Objects gave us fine-grained control as well as better availability as they run in our edge data centers. Additionally, each waiting room is isolated from the others: adverse events affecting one customer are less likely to spill over to other customers.

Implementation with Durable Objects
Based on these advantages, we decided to build our product on Durable Objects.

As mentioned above, we use a worker to decide whether to send users to the Waiting Room or the web application. That worker periodically sends a request to a Durable Object saying how many users it sent to the Waiting Room and how many it sent to the web application. A Durable Object instance is created on the first request and remains active as long as it is receiving requests. The Durable Object aggregates the counters sent by every worker to create a count of users sent to the Waiting Room and a count of users on the web application.

Building Waiting Room on Workers and Durable Objects

A Durable Object instance is only active as long as it is receiving requests and can be restarted during maintenance. When a Durable Object instance is restarted, its in-memory state is cleared. To preserve the in-memory data on Durable Object restarts, we back up the data using the Cache API. This offers weaker guarantees than using the Durable Object persistent storage as data may be evicted from cache, or the Durable Object can be moved to a different data center. If that happens, the Durable Object will have to start without cached data. On the other hand, persistent storage at the edge still has limited capacity. Since we can rebuild state very quickly from worker updates, we decided that cache is enough for our use case.

Scaling up
When traffic spikes happen around the world, new workers are created. Every worker needs to communicate how many users have been queued and how many have been let through to the web application. However, while workers automatically scale horizontally when traffic increases, Durable Objects do not. By design, there is only one instance of any Durable Object. This instance runs on a single thread so if it receives requests more quickly than it can respond, it can become overloaded. To avoid that, we cannot let every worker send its data directly to the same Durable Object. The way we achieve scalability is by sharding: we create per data center Durable Object instances that report up to one global instance.

Building Waiting Room on Workers and Durable Objects
Durable Objects implementation

The aggregation is done in two stages: at the data-center level and at the global level.

Data Center Durable Object
When a request comes to a particular location, we can see the corresponding data center by looking at the cf.colo field on the request. The Data Center Durable Object keeps track of the number of workers in the data center. It aggregates the state from all those workers. It also responds to workers with important information within a data center like the number of users making requests to a waiting room or number of workers. Frequently, it updates the Global Durable Object and receives information about other data centers as the response.

Worker User Slots

Above we talked about how a data center gets user slots allocated to it based on the past traffic patterns. If every worker in the data center talks to the Data Center Durable Object on every request, the Durable Object could get overwhelmed. Worker User Slots help us to overcome this problem.

Every worker keeps track of the number of users it has let through to the web application and the number of users that it has queued. The worker user slots are the number of users a worker can send to the web application at any point in time. This is calculated from the user slots available for the data center and the worker count in the data center. We divide the total number of user slots available for the data center by the number of workers in the data center to get the user slots available for each worker. If there are two workers and 10 users that can be sent to the web application from the data center, then we allocate five as the budget for each worker. This division is needed because every worker makes its own decisions on whether to send the user to the web application or the waiting room without talking to anyone else.

Building Waiting Room on Workers and Durable Objects
Waiting room inside a data center

When the traffic changes, new workers can spin up or old workers can die. The worker count in a data center is dynamic as the traffic to the data center changes. Here we make a trade off similar to the one for inter data center coordination: there is a risk of overshooting the limit if many more workers are created between calls to the Data Center Durable Object. But too many calls to the Data Center Durable Object would make it hard to scale. In this case though, we can use Cache for faster synchronization within the data center.

Cache

On every interaction to the Data Center Durable Object, the worker saves a copy of the data it receives to the cache. Every worker frequently talks to the cache to update the state it has in memory with the state in cache. We also adaptively adjust the rate of writes from the workers to the Data Center Durable Object based on the number of workers in the data center. This helps to ensure that we do not take down the Data Center Durable Object when traffic changes.

Global Durable Object

The Global Durable Object is designed to be simple and stores the information it receives from any data center in memory. It responds with the information it has about all data centers. It periodically saves its in-memory state to cache using the Workers Cache API so that it can withstand restarts as mentioned above.

Building Waiting Room on Workers and Durable Objects
Components of waiting room

Recap

This is how the waiting room works right now. Every request with the enabled waiting room goes to a worker at a Cloudflare edge data center. When this happens, the worker looks for the state of the waiting room in the Cache first. We use cache here instead of Data Center Durable Object so that we do not overwhelm the Durable Object instance when there is a spike in traffic. Plus, reading data from cache is faster. The workers periodically make a request to the Data Center Durable Object to get the waiting room state which they then write to the cache. The idea here is that the cache should have a recent copy of the waiting room state.

Workers can examine the request to know which data center they are in. Every worker periodically makes a request to the corresponding Data Center Durable Object. This interaction updates the worker state in the Data Center Durable Object. In return, the workers get the waiting room state from the Data Center Durable Object. The Data Center Durable Object sends the data center state to the Global Durable Object periodically. In the response, the Data Center Durable Object receives all data center states globally. It then calculates the waiting room state and returns that state to a worker in its response.

The advantage of this design is that it’s possible to adjust the rate of writes from workers to the Data Center Durable Object and from the Data Center Durable Object to the Global Durable Object based on the traffic received in the waiting room. This helps us respond to requests during high traffic without overloading the individual Durable Object instances.

Conclusion

By using Workers and Durable Objects, Waiting Room was able to scale up to keep web application servers online for many of our early customers during large spikes of traffic. It helped keep vaccination sign-ups online for companies and governments around the world for free through Project Fair Shot: Verto Health was able to serve over 4 million customers in Canada; Ticket Tailor reduced their peak resource utilization from 70% down to 10%; the County of San Luis Obispo was able to stay online during traffic surges of up to 23,000 users; and the country of Latvia was able to stay online during surges of thousands of requests per second. These are just a few of the customers we served and will continue to serve until Project Fair Shot ends.

In the coming days, we are rolling out the Waiting Room to customers on our business plan. Sign up today to prevent spikes of traffic to your web application. If you are interested in access to Durable Objects, it’s currently available to try out in Open Beta.